Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=WaJsPikptyo
CAUTION – Acrobatic Seed Dispersal in Progress #PteropusPoliocephalus
Post Syndicated from Matt Granger original https://www.youtube.com/shorts/kp7lTfclZYg
Comic for 2026.08.24 – Bar
Post Syndicated from Explosm.net original https://explosm.net/comics/bar
New Cyanide and Happiness Comic
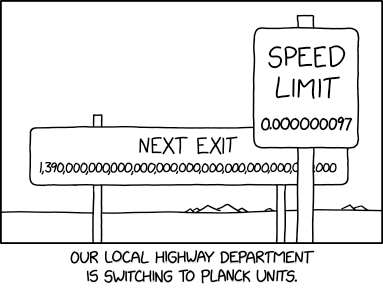
Highway Signs
Post Syndicated from xkcd.com original https://xkcd.com/3289/
d-Matrix Raptor 3D-DRAM Accelerator for Generative Inference at Hot Chips 2026
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/d-matrix-raptor-3d-dram-accelerator-for-generative-inference-at-hot-chips-2026/
At Hot Chips 2026, d-Matrix showed off its Raptor 3D-DRAM accelerator for AI breaking free of using HBM for memory by stacking DRAM and logic
The post d-Matrix Raptor 3D-DRAM Accelerator for Generative Inference at Hot Chips 2026 appeared first on ServeTheHome.
SK hynix HBM Packaging at Hot Chips 2026
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/sk-hynix-hbm-packaging-at-hot-chips-2026/
At Hot Chips 2026 SK hynix presented some of the challenges around HBM and packaging the memory for AI accelerators
The post SK hynix HBM Packaging at Hot Chips 2026 appeared first on ServeTheHome.
Samsung Evolving HBM Base Die at Hot Chips 2026
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/samsung-evolving-hbm-base-die-at-hot-chips-2026/
At Hot Chips 2026, Samsung discussed how it plans to evolve the HBM base die to free up more package area for mroe efficient compute
The post Samsung Evolving HBM Base Die at Hot Chips 2026 appeared first on ServeTheHome.
Micron Evolving Memory Architectures for AI at Hot Chips 2026
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/micron-evolving-memory-architectures-for-ai-at-hot-chips-2026/
At Hot Chips 2026, Micron discussed how memory architectures are evolving for AI and some of the current packaging opportunities
The post Micron Evolving Memory Architectures for AI at Hot Chips 2026 appeared first on ServeTheHome.
Comic for 2026.08.23 – Running With Scissors
Post Syndicated from Explosm.net original https://explosm.net/comics/running-with-scissors
New Cyanide and Happiness Comic
S10 E13: Gaza War, Congress & Food Safety: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=FG4RX9uC6dE
Sunday’s stable kernel set
Mourning Steve French
Post Syndicated from corbet original https://lwn.net/Articles/1090098/
From Jeremy Allison we have the
sad news of the passing of Steve French. He was the maintainer of the
kernel’s SMB filesystem code for many years, having only dropped that
role due to health issues in the last week. “I’ve known Steve for
” He will indeed be missed.
over 20 years. He was a legend in the community, and a really good
friend. He will be greatly missed. Farewell Steve.
Чии са фейсбук троловете?
Post Syndicated from Bozho original https://blog.bozho.net/blog/4622
„Троловете са на ДБ и ПП“. Тази лъжа тръгна от интервю вицепремиера по пропагандата Иво Христов и се поде от всякакви говорители, политици, журналисти.
Разбира се, ние в Демокртична България тролове нямаме.
Няколкото фейсбук страници, които бъркат в здравето на политическите манипулатори, не са наши и дори не познаваме хората, които стоят зад тях (с изключение на един от хората зад страницата BG Elves, когото познавам като местен активист).
Дали е редно политически мнения да се разпростаняват под псевдоним е отделен въпрос. Аз смятам, че е допустимо и част от културата в интернет. Но дори на страницата да пишеше „Зад страницата стои Иван Георгиев от Горна Оряховица“, нямаше да има особена разлика.
Но „трол“ значи друго и има друга цел – троловете са фалшиви профили, в общия случай без зад тях да стоят истински хора, чиято цел е да разпространяват и усилват дадено послание. Тролове могат да бъдат и обикновени хора, които със собственити си профили срещу заплащане да правят същото. А има и хибриден вариант, при който се плаща на обикновени хора да си направят по няколко акаунта – има такива репортажи по националните ни телевизии. Затова се говори за „ферми“ или „фабрики“ с тролове – защото бройката е много важна, за да бъдат подлъгани алгоритмите на социалните мрежи, че съдържанието, което харесват, споделят или създават е масово мнение.
Ние не само нямаме тролове, а сме единствената политическа сила, която е правила опити да намери решение на този проблем. И ще дам три примера.
През 2023 г. представихме публично законопроект, който целеше в определени случаи (допустими от гледна точка на хармонизираното европейско право) да задължим социалните мрежи да установяват координирано неавтентично поведение (т.е. профили, действащи по команда, най-често автоматизирано, да коментират/харесват/разпространяват дадено съдържание). Със законопроекта се предлагаха решения и на други канали за разпространение на пропаганда и дезинформация – напр. монетизирането на сайтове за фалшиви новини чрез фалшиви реклами – на хранителни добавки, фалшиви лекарства и др.
Тогава много от хората, които сега обясняват кой имал тролове, скочиха и казаха „сакън, цензура!“. Цензура, разбира се, нямаше, и от нас никога не би излязло нещо, което да отваря вратата за цензура, но тогава опитът за справяне с троловете беше удавен в такива заглавия и нравоучения.
През 2022 г., докато бях министър, на събитие в Давос, организирано от Украйна, говорих за ролята на социалните мрежи в борбата с разпространението на съдържание чрез координирано неавтентично поведение (тролове). Тогава имаше доклад на Фейсбук, че в месеците около нахлуването на Русия в Украйна, Фейсбук са свалили 2 фалшиви профила, свързани с Русия. Да, 2. Абсолютен провал – всички знаехме и виждахме какво се случва в социалните мрежи.
В този период имахме и срещи и кореспонденция с Мета на високо ниво. Изпратихме конкретно предложение – българското фейсбук пространство да бъде обект на задълбочено изследване за координирано неавтентично поведение. Мета отказа. В резултат на този отказ се роди и гореспоменатия законопроект.
Тогава от Мета ни попитаха „защо не използвате директния канал за докладване на съдържание“, на което моят отговор беше „защото не може правителството да казва кое е вярно и кое е грешно – ваша работа е да установите проблеми с поведението, а не със самото съдържание“.
Тази разлика е съществена. Винаги думата „цензура“ се появява, когато някой опита да говори по тази тема. А никога, по никакъв повод не е ставало дума за това държавата да определя кое е вярно и кое е „фалшива новина“ – това е гршено, опасно и не работи.
Пак тогава, през 2022 г. имах среща с двама еврокомисари в Брюксел – Тиери Бретон и Вера Йорова по отношение на същия проблем с троловете. Бретон поиска доклад с примери, какъвто подготвихме и му изпратих. Йоурова потвърди, че наблюдават същите проблеми с троловете и пропагандните наративи в Чехия, а и в много други източноевропейски държави. За съжаление Актът за цифровите услуги на ЕС беше в твърде напреднала фаза тогава и не беше възможно да се предложат допълнителни гаранции, че тролове няма да се използват за усилване на съдържание.
Все пак, Актът за цифровите услуги даде инструментариум на Европейската комисия да изисква мерки срещу това поведение. И това дава някакъв резултат. В последната предизборна кампания ТикТок свали 34 фалшиви профила на ДПС.
А Иво Христов вероятно може да разкаже повече за това кои профили, промотиращи Прогресивна България са били свалени от ТикТок и защо. Вероятно затова тогава Радев подскочи и заговори за „румънски сценарий“ ни в клин, ни в ръкав. Може би има обяснение и за десетките профили, пускащи едно също съдържание в подкрепа на ПБ, които бяха осветени в последните дни.
Пиша всичко това, за да не бъде подменяна реалността – нещо, което вероятно е добре описано в кремълските учебници по пропаганда. Учебници, които са успешно адаптирани за дигиталната ера.
Но както писах и онзи ден по друг повод – би било грешка да обвиним руската пропаганда за всички несгоди – най-малкото защото има достатъчно местни играчи, които си мислят, че като платят на „агенция“, която да организира тролски профили да им слагат сърчица, ще подквасят политическото море.
Различното мнение не значи, че някой е трол. Установяването на тролове е много лесно за Фейсбук и много трудно за странични наблюдатели, които не разполагат с метаданни. Трудно е, но не невъзможно да бъде намерено решение на този проблем и призовавам да търсим такова, вместо вицепремиери да си споделят фрустрациите от 3-4 анонини страници.
Материалът Чии са фейсбук троловете? е публикуван за пръв път на БЛОГодаря.
Calculus
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/calculus/
S10 E12: Tennessee Mayoral Race & Homeschooling: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=juCyYV7kauw
Patrick at Micro Center Columbus Ohio Grand Reopening with Jeff Geerling
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/patrick-at-micro-center-columbus-ohio-grand-reopening-with-jeff-geerling/
Patrick and Jeff Geerling are at the Micro Center in Columbus, Ohio for the new store’s grand reopening today
The post Patrick at Micro Center Columbus Ohio Grand Reopening with Jeff Geerling appeared first on ServeTheHome.
What If Russia and China Launch Two Wars at Once?
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/DF7Ns4tr2q0
The Indian Wave Machine
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=x0og-gbDPTs
Say it once: introducing Bot Preference Sync
Post Syndicated from Jin-Hee Lee original https://blog.cloudflare.com/bot-preference-sync%20/
We’re constantly building for the different goals of our customers. Some customers want to optimize for discovery, while others want to protect their content with the strictest security policy. Among these differing policies, there are multiple ways to mitigate bot traffic. Some mechanisms simply state your preference, assuming best intent from crawlers, and other approaches actually lock down content by outright blocking with a Bot Management solution.
We recognize that it's cumbersome to maintain multiple layers of protection on your website. For example, there are cases in which your robots.txt states that a crawler is Disallowed from accessing your website, while your enforcement rules actually don’t block that crawler. When your stated preferences and your enforced rules disagree, some crawlers treat it as a basis to disregard your preferences or try to bypass your enforced rules.
A couple of years ago, Cloudflare announced an easier way to disallow AI training on your website by tackling two of these layers: a managed value of robots.txt that told a fixed list of major Training crawlers not to train on your content, along with edge-enforced blocks to Training crawlers. On July 1, 2026, we launched easier options to manage different kinds of AI traffic use cases. You can say what you want to do about Search, Agent, and Training traffic on your website.
We're announcing Bot Preference Sync, available to all customers from the Free tier to Enterprise. Bot Preference Sync reflects what you've set in your AI bot configuration by updating corresponding preferences to your robots.txt, and it can be turned on or off at any time. No more static file for one use case: we'll help you tailor your robots.txt to reflect what you’ve already configured for different AI bot categories.
New questions facing the Internet
For years, the most pressing question in this space was: "Is my content being used to train AI models without my permission?" It's an important question, and it isn't going away. Alongside this, the questions we increasingly hear are about discoverability and engagement. How do I show up when someone asks an AI assistant something my site can answer? How much of my traffic is coming from AI crawlers versus real people? What content is actually driving referrals, and what is it worth?
The answers differ by business model. Discoverability and engagement are key, top-of-mind issues for any businesses trying to thrive on the modern web, but the funnels for these are different: an e-commerce store may want everything crawled and trained on, so its products surface when a shopper asks a chatbot for "the best sofa for a small apartment." A publisher that monetizes pages with ads may want the opposite: stay in the search index that sends readers to the page, but keep its articles out of model training and, crucially, be able to verify that its content really wasn't used without permission.
There's no single right answer, which is exactly the point. Your controls should reflect your strategy, which is why we've been building tools to give you visibility and choice at every layer. Bot Preference Sync ties these together, so the preference you set is the preference you publish.
The call for Transparency
On July 1, 2026, we made the case that mixed-use crawlers, or “bots that blend search, agent use, and training behind a single user agent,” put site owners at a disadvantage precisely because they make it hard to separate what you want from what you don't. That's still true, and our position on Transparency for site owners hasn't changed.
But there’s more than one way to approach Transparency. We want to reward the operators who are clear about their identity and how they are using the data they crawl. For purposes of bot Verification, the owners of bots that perform both Search and Training will need to provide additional information in order to not be blocked when “Disallow Training” is set. Those requirements are:
- The bot must respect, via any mechanism, a “no training” preference in robots.txt
- They give site owners a way to opt out of AI summaries.
- They provide URL-level visibility into which pages were made available for training, as well metrics on search results, so you can see how your content was used for search and for training.
- They can show publicly that Disallowing Training does not hurt your traditional search results.
Bots of leading AI models and service providers that meet these criteria are tracked publicly in the AI bot transparency section in Cloudflare Radar, which includes examples in which best practices are honored, as well as when they are not. Crawlers that don't provide Transparency will not get the benefit of the doubt — they're still blocked when you disallow training. In other words, this is a way of making Transparency the price of admission.
Introducing Bot Preference Sync
Bot Preference Sync is a new feature that keeps your robots.txt reflecting the AI bot preferences you've already set for Search, Agent, and Training on the Cloudflare zone-level dashboard. If a site owner already has a robots.txt file, the contents added by Bot Preference Sync will be prepended to the existing material, so any existing Disallow directives are maintained.
Instead of a site owner maintaining a separate static file, Cloudflare generates or updates your robots.txt based on your configuration, so what you say to the world and what you enforce at the edge are kept in sync.
For Search and Agent, the three options we announced on July 1 remain: Allow, Block on pages that serve ads, or Block everywhere. For Training, we’re refining the option to stop your content being used for training models with the Disallow option:
Disallow: a "no training" preference is written to your robots.txt, so that cooperating mixed-use crawlers who take the extra Transparency step can still access your content for search indexing, since they’re allowing site owners to directly verify how their data is used. Cooperating crawlers honor the preferences in robots.txt, and your Search visibility for cooperating crawlers is unaffected.
Let’s take the example below, in which someone has configured their AI bot policy to say “Allow Search, Allow Agents, Disallow Training.”
Since this example site has Bot Preference Sync on, their robots.txt would prepend something like the following (which has been shortened and anonymized for the sake of the example):
We’ll use bots that we track in BotBase to periodically update the list of bots that is added to robots.txt when you choose to Block or Disallow a given category. The Verified bots that are classified as Search, Agent, and Training can be viewed at any time in our public bots directory.
For all new customers, Bot Preference Sync will be on by default, to make it easier to manage blocks and preferences that reflect the same policy. For existing customers who are using the legacy managed robots.txt feature, we'll prompt you to review and confirm your preferences to transition to the new Bot Preference Sync upon its upcoming launch.
Some customers may want or need to be more hands-on in stating their preferences, for example, if they have a special arrangement with a given company to which they want to grant an exception. Because Bot Preference Sync is designed to tackle policy decisions made category-wide rather than case-by-case, it will not directly read from individual custom rules with more complex logic. Customers with a more fine-tuned security policy always have the option to turn off the sync that sets group policies, and tailor their file to match their custom policy.
We’re also making a change that allows publishers or ad-supported sites to have a different default from other site owners. We’ve created a default to make it easier for publishing sites that rely on ads and expect them to be reserved for human visitors. At the time of onboarding, such customers can select the option, “I monetize from pages with ads on this domain", which will set Training to Disallow as the default. (Customers have the choice to change this setting at any time.) This way, you stay in search while keeping your content out of model training.
For the non-publisher case, new customers will not have any blocks or disallows added by default when they onboard a domain: the choice is up to the customer. You can choose if you want to block Search or Agent or Training at any point, but the starting point will not add any blocks on your behalf.
What's next?
Bot Preference Sync will be available to all customers, on every plan, in the coming week. Keep an eye on our changelog for availability, and watch your dashboard (and inbox) for the prompt to confirm your preferences!
This is one step in a longer effort. We'll keep working with the large bot operators to make sure we're not compromising on familiar challenges (like training without consent) nor emerging questions (like discoverability and engagement). Beneath it all is our effort to promote greater Transparency and control for site owners.
Friday Squid Blogging: Neon Flying Squid
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/friday-squid-blogging-neon-flying-squid.html
The neon flying squid can fly in formation.
The shoal of about 100 squid rose unexpectedly from a patch of the Pacific Ocean around 370 miles from Tokyo and glided near the boat for about 30 metres. The astonished researchers were the first to capture photographs of such a thing, which looked like the early stages of an alien invasion.
They were probably neon flying squid (Ommastrephes bartramii), the subsequent study states, a species that is part of a 20-strong flying squid family that was known to leap from the water but, until then, was only rumoured to also be able to glide above it.
The neon flying squid was able to gain such elevation by using the hyponome, a funnel-like muscular organ also present in other cephalopods, such as octopuses. The organ is able to force water out in a jet, propelling the body along both in and out of the sea. Photographs of the gliding squid show them with their arms (they have 10 limbs in all) splayed outwards.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.