Without proper controls, website owners have long faced a difficult tradeoff: allow your content to be used for AI training, or risk losing discoverability in search. That tradeoff exists because some of the largest organizations on the Internet use mixed-use crawlers: a single crawler serving both search and AI training. Refuse one, and you refuse the other.
Today, Cloudflare is announcing a new Disallow AI Training setting that lets you easily stay indexed for search while refusing to let that same crawler train on your content. Apple, Google, and Microsoft honor or have committed (in a specified time frame) to honor this setting.
Mixed-use crawlers were the hard part of the training question. AI Summaries are next. A site-wide yes or no is too blunt: how much of your content appears in a summary matters as much as whether it appears at all. An opt-out for AI summaries is already one of the requirements we've set for mixed-use crawler operators. By early next year, our goal is to let you control how much of your content is included — set once on Cloudflare, rather than with each operator separately.
Why asking isn’t enough
Most site owners want to be found: by humans, agents, and (good) bots. But a significant portion of the open Internet is funded by advertising, subscriptions, or direct relationships with visitors, and those models only pay when someone actually arrives.
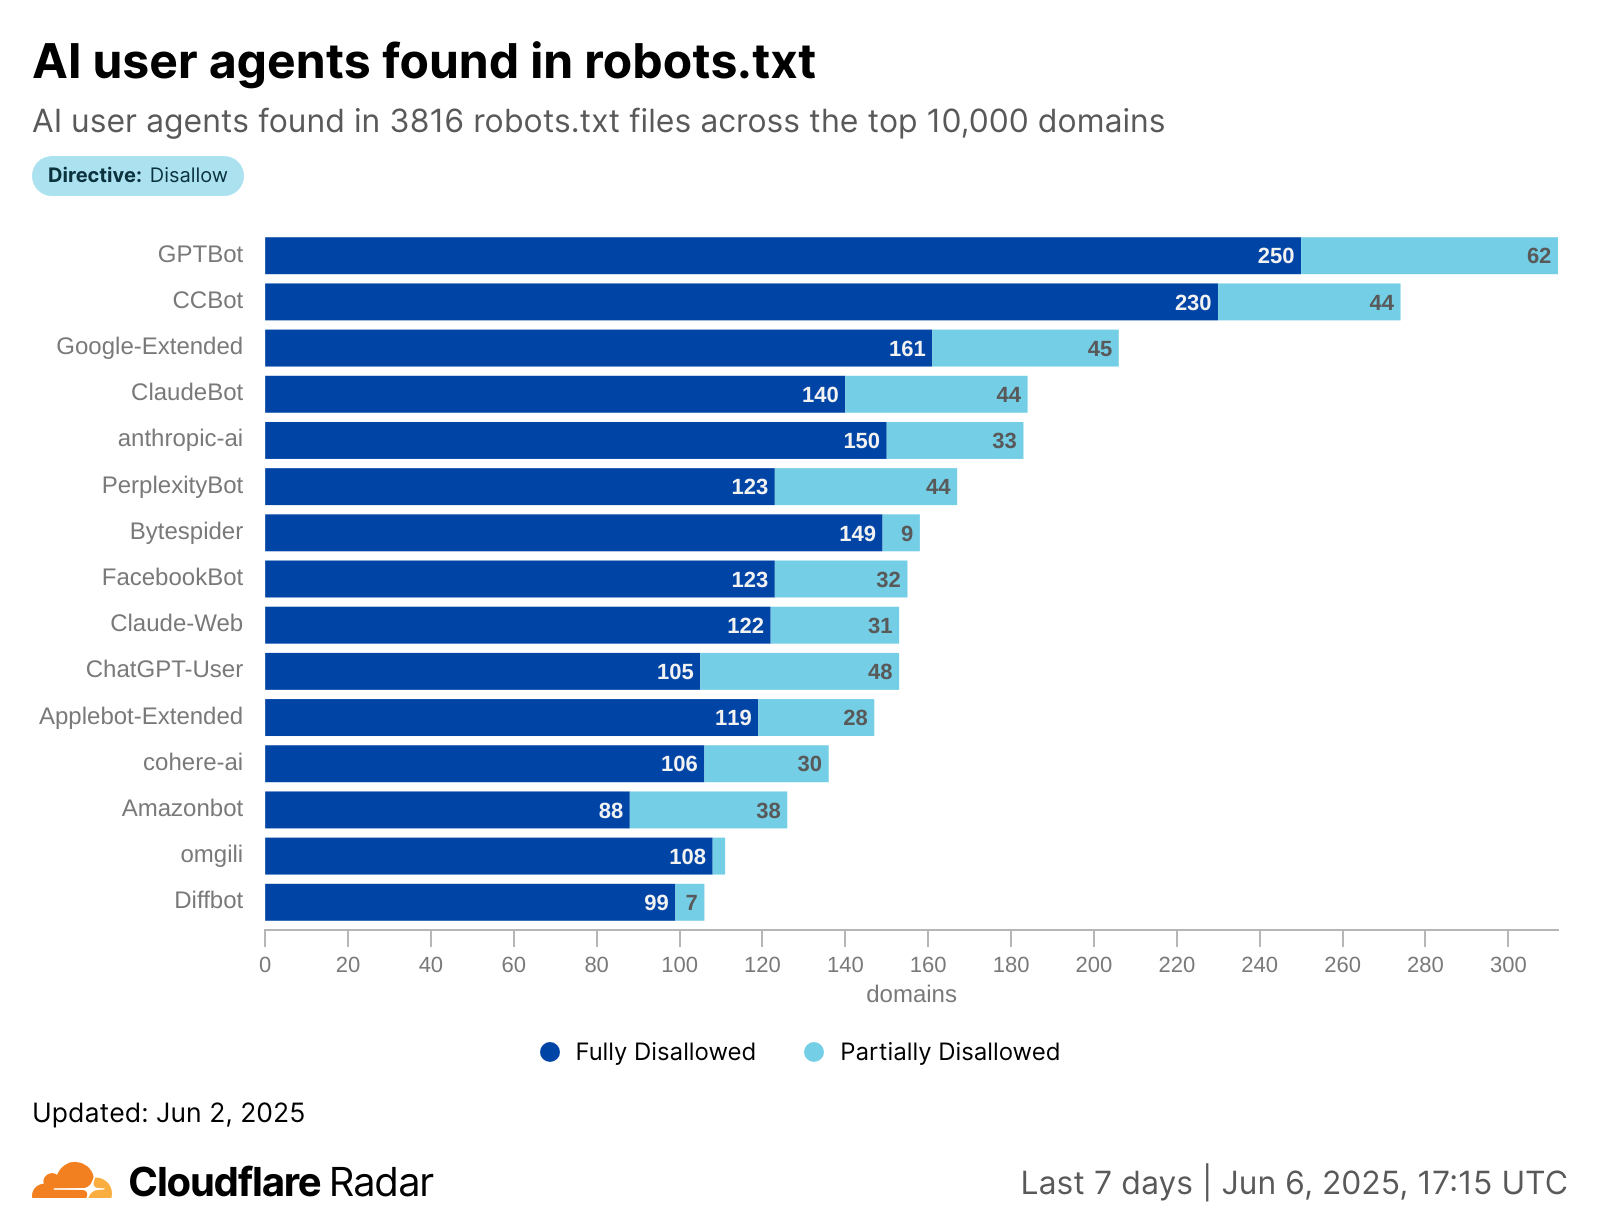
Almost every site owner considers Search beneficial: less than 1% of Cloudflare sites choose to block Search bots. Training, however, is a different story: 17% of sites choose to enable some mechanism to block training. This is exactly why we decided site owners needed more granular controls, rather than a one-size-fits-all “Block AI.”
A robots.txt directive alone cannot solve this problem. Anyone can publish one, but it cannot identify who is crawling, determine why they are crawling, or stop a crawler that ignores it.
A network can solve it, however: we publish the preference, identify who is crawling, classify why they are crawling, and block the ones that ignore it – then report what each operator actually does on Radar.
But blocking removes a crawler. It doesn't change how crawlers behave. The better outcome is operators that don't make you choose at all. So since July, we've been talking to them directly. The response has been encouraging: almost all agreed that site owners should have control and transparency into how their content is used, and reassurance that their choices will be respected. To help site owners understand that, we created a designation: Accountable.
The Accountable designation recognizes both capabilities available today and concrete commitments to deliver them. To qualify, a bot operator must meet or commit to meeting the following requirements:
A mechanism for site owners to opt out of AI training, through robots.txt or a similar standard.
A mechanism for site owners to opt out of AI summaries set with the operator directly, and next year through Cloudflare (see section below for more detail).
URL-level visibility into which pages were made available for training, along with metrics showing how content appeared in search.
Assurance that opting out of AI training will not affect traditional search results.
Apple, Google, and Microsoft all demonstrate that they meet the qualifications to be Accountable. Each combines capabilities available today with time-bound commitments for those still in development. The details of each of these companies’ crawlers are shared below.
New security setting options
Cloudflare classifies bots by behavior, and a single bot can exhibit more than one behavior. Three behaviors are available as controls:
Search – crawling to build a search index.
Training – crawling to train or fine-tune a model.
Agent – user-directed agents visiting a page on behalf of a human, such as chat fetch bots and browser-use agents.
A mixed-use crawler is a single crawler doing both Search and Training. Without controls, that combination creates the tradeoff described above: site owners cannot refuse one use without refusing the other.
To avoid blocking Accountable mixed-use crawlers — the ones that don't force that tradeoff on website owners — we are introducing a new setting: Disallow AI Training. Disallow AI Training is named for the Disallow: directive it publishes in your robots.txt.
“Block” setting now means something different
Block and “Block on pages with ads” previously did not apply to mixed-use crawlers because blocking them could also affect search discoverability. Now that we have the new Disallow AI Training setting, Block and “Block on pages with ads” apply to all training crawlers, including mixed-use crawlers.
Training, Search, and Agent controls are applied at the domain level. With the addition of Disallow AI Training, the available settings are:
Allow: All crawlers are allowed, unless blocked by another setting or a WAF rule.
Disallow AI Training: Bot Preference Sync publishes the applicable no-training preference in robots.txt. Accountable mixed-use crawlers remain allowed for search. Every other training crawler is blocked, including the training-only crawlers run by Amazon, Anthropic, Meta, and OpenAI — blocking those does not affect search. Disallow AI Training is only available as a setting for Training, not Search or Agent.
Block on pages with ads: Crawlers, including mixed-use crawlers, are blocked only on pages detected to be serving an ad.
Block: All crawlers, including mixed-use crawlers, are blocked.
Disallow AI Training works by publishing a preference in robots.txt. An ads-only preference cannot be expressed that way: Cloudflare can detect which pages serve ads, but that list is too large and changes too frequently to enumerate in robots.txt. That's why there's no Disallow AI Training on pages with ads.
Agents do not create the same search-discoverability tradeoff as mixed-use crawlers, and the Internet does not yet have a well-established directive for expressing Disallow preferences to agents. For now, we’re not including a Disallow setting for Agents. As standards such as ai-prefs mature, we will revisit this approach.
What changes on September 15?
We are making the following changes to Bot Management and AI Crawl Control:
Block and Block on pages with ads now apply to mixed-use crawlers, including Applebot, Bingbot, and Googlebot, so either setting impacts search as well as training. To stop training and keep search, use Disallow AI Training.
“Block AI Bots” will be deprecated in favor of the more granular Search, Training, and Agent controls.
Managed Robots.txt will be deprecated in favor of Bot Preference Sync. Customers who enabled Managed Robots.txt will migrate to the new system.
Disallow AI Training will become part of the recommended configuration for certain new domains.
Existing customers will have their preferences migrated to the new controls as described below.
What you need to do
Nothing, in almost every case. Your current settings carry over on their own.
If you want mixed-use crawlers gone entirely, you now have to say so. Select Block. It will stop Applebot, Bingbot, and Googlebot from reaching your site — search included.
Existing domains that never used the Search/Training/Agent controls
Site owners that never configured the more granular controls will be migrated to the new settings based on their legacy Block AI Bots setting:
Existing domains that previously configured the Search/Training/Agent controls
For domains that previously configured the granular controls, we will preserve the practical effect of their selections under the new definitions. Previous Training selections of Block or Block on pages with ads will migrate to Disallow AI Training.
Recommendations for new domains
Beginning September 15, customers onboarding a new domain will be offered one of two preset configurations, depending on whether the site earns money from advertising. Ad revenue depends on a human actually seeing the page. Training replaces that visit with an answer; agents fetch the page with nobody there to see the ads. So the presets for ad-supported sites are more restrictive. You can change any of these settings during onboarding, or at any time afterward.
Recommended settings for new domains.
What does this mean for specific mixed-use crawlers?
Applebot, Bingbot, and Googlebot are Accountable. Apple, Google, and Microsoft are committed to the same principles of publisher choice and transparency. Under Disallow AI Training they can keep crawling your site for search. Selecting Block stops them entirely.
We also categorize the relevant crawlers from Amazon, Anthropic, Meta, and OpenAI as Accountable. These organizations separate their Search and Training crawlers, so Cloudflare can block the Training crawler without affecting search.
Applebot
Applebot allows site owners to opt out of training by adding a Disallow rule to robots.txt for “Applebot-Extended”. Site owners can also currently express preferences for AI Summaries via their nosnippet directive in the page HTML. Content can also be labeled as paywalled content to exclude it from generative output. Applebot does not yet provide a tool for URL-level inspection. However, we have met with their team, and they have shared details of their in-progress solution for next year. Apple has also stated that disallowing training does not impact search ranking.
Googlebot
Googlebot allows site owners to opt out of training by adding a Disallow rule to robots.txt for “Google-Extended”, and they provide a toggle inside their webmaster portal to exclude a site’s content from generative search results. Googlebot also provides site owners with metrics and reporting regarding search results and AI summary results. Google shared information about their existing and recently launched controls, as well as information about what they're already working on, including additional URL-level transparency tools for site-owners related to Google-Extended, which they expect to launch in the weeks to come. Google has also stated that disallowing Google-Extended does not impact search ranking.
Bingbot
Bingbot provides granular controls and transparency in their Webmaster Tools. Site owners can currently express AI training preferences through Bing’s NOARCHIVEmeta tag. Microsoft is extending these capabilities and currently building the mechanism to also respect a “no training” preference in robots.txt at the domain/site level, targeted for early 2027. For Cloudflare Customers who wish to opt out of training in Bing today, in addition to using the NOARCHIVE tag, site owners can use the Block URLs or Content Removal tool. Microsoft has also stated that using NOARCHIVEwill not impact search ranking.
Until that support launches, selecting Disallow AI Training will not automatically convey a no-training preference to Bing through robots.txt. This is the same practical behavior as the previous Training Block setting, which did not apply to mixed-use crawlers such as Bingbot.
Continuing progress
We will continue to reach out and engage with all operators of AI crawlers as these capabilities evolve. Cloudflare Radar publicly tracks the controls, transparency, and reporting provided by Accountable crawler operators.
Making the Internet better requires both sides to have agency: crawlers need access to the open web, and the people who create that web need meaningful control over how their work is used. Today’s announcement represents concrete progress toward that balance.
Progress requires infrastructure providers, content creators, technology companies, and standards bodies such as the Internet Engineering Task Force (IETF) working together to translate these principles into open, interoperable standards.
What’s next: AI Summaries
Training and AI Summaries raise different questions for site owners. Training concerns whether content can be used to build AI models. Summaries affect how people discover, evaluate, and ultimately visit a business. Both matter, but they affect businesses in different ways.
Controls to opt out of AI summaries are the first step. The operators identified as Accountable either provide or are completing work to provide that capability, establishing an important baseline: site owners can say no.
But a site-wide choice between allowing and prohibiting summaries is still a blunt instrument. The right decision depends on the site, the content, and the business outcome. For publishers, training raises foundational questions about control, compensation, and the sustainability of original content. Summaries create a separate and often more immediate distribution question: does someone visit the publisher’s site, or consume the answer within a search or AI experience? For many other businesses, AI summaries increasingly sit between a potential customer and a website. They may answer a question, compare alternatives, recommend a product, or help someone decide whether to visit at all.
The data illustrates mixed impact. More than half of consumers read summaries in Search, and those consumers are over 40% more likely to end their search after reading one. This can reduce the number of visits a website receives. But consumers referred by AI Search convert at between three times and over five times the rate of those referred by traditional search. AI may produce fewer visits while sending customers with much greater intent.
That is not inherently good or bad. A publisher funded by advertising may optimize for audience volume. A retailer may prefer fewer visitors who are more likely to purchase. Cloudflare’s role is not to choose for them, but to provide the visibility and control needed to make an informed decision.
Summary opt-outs are a strong start, but they are not the end state. Our next focus is helping site owners understand how summaries affect their businesses and giving them more control over how much of their content can be used. Open standards such as ai-prefs will be an important part of making that possible.
If you would like to have a voice in this conversation, or provide feedback, please reach out to [email protected].
These new controls are available to all customers, on all plans, and can be configured at the domain (zone) Security Settings. Not on Cloudflare yet? Start for free to set the traffic controls that you want today.
Last month, on our second Content Independence Day, we announced a couple of features designed to give website owners more visibility and control over automated traffic: BotBase added a searchable directory of known bots to the Cloudflare dashboard, while Business Insights helped owners understand how crawlers interact with their content. We know that the ecosystem of bots is vast, making it all the more important for site owners to be able to manage bot traffic sustainably.
But this ecosystem goes both ways. While website owners need to decide which automated traffic they allow, bot operators need a clear way to identify themselves, explain what their bots do, and keep that information current. BotBase works best when both sides can participate.
When we launched BotBase, we said we would build tools to bring bot operators into this ecosystem. Until now, their experience largely ended at submission. After pressing submit, an operator had no easy way to check the submission's status, understand why it was rejected, or update an existing entry. Today, we start to change that with the launch of BotBase for Operators, tackling what bot operators need first: transparency.
A new home for bot submissions
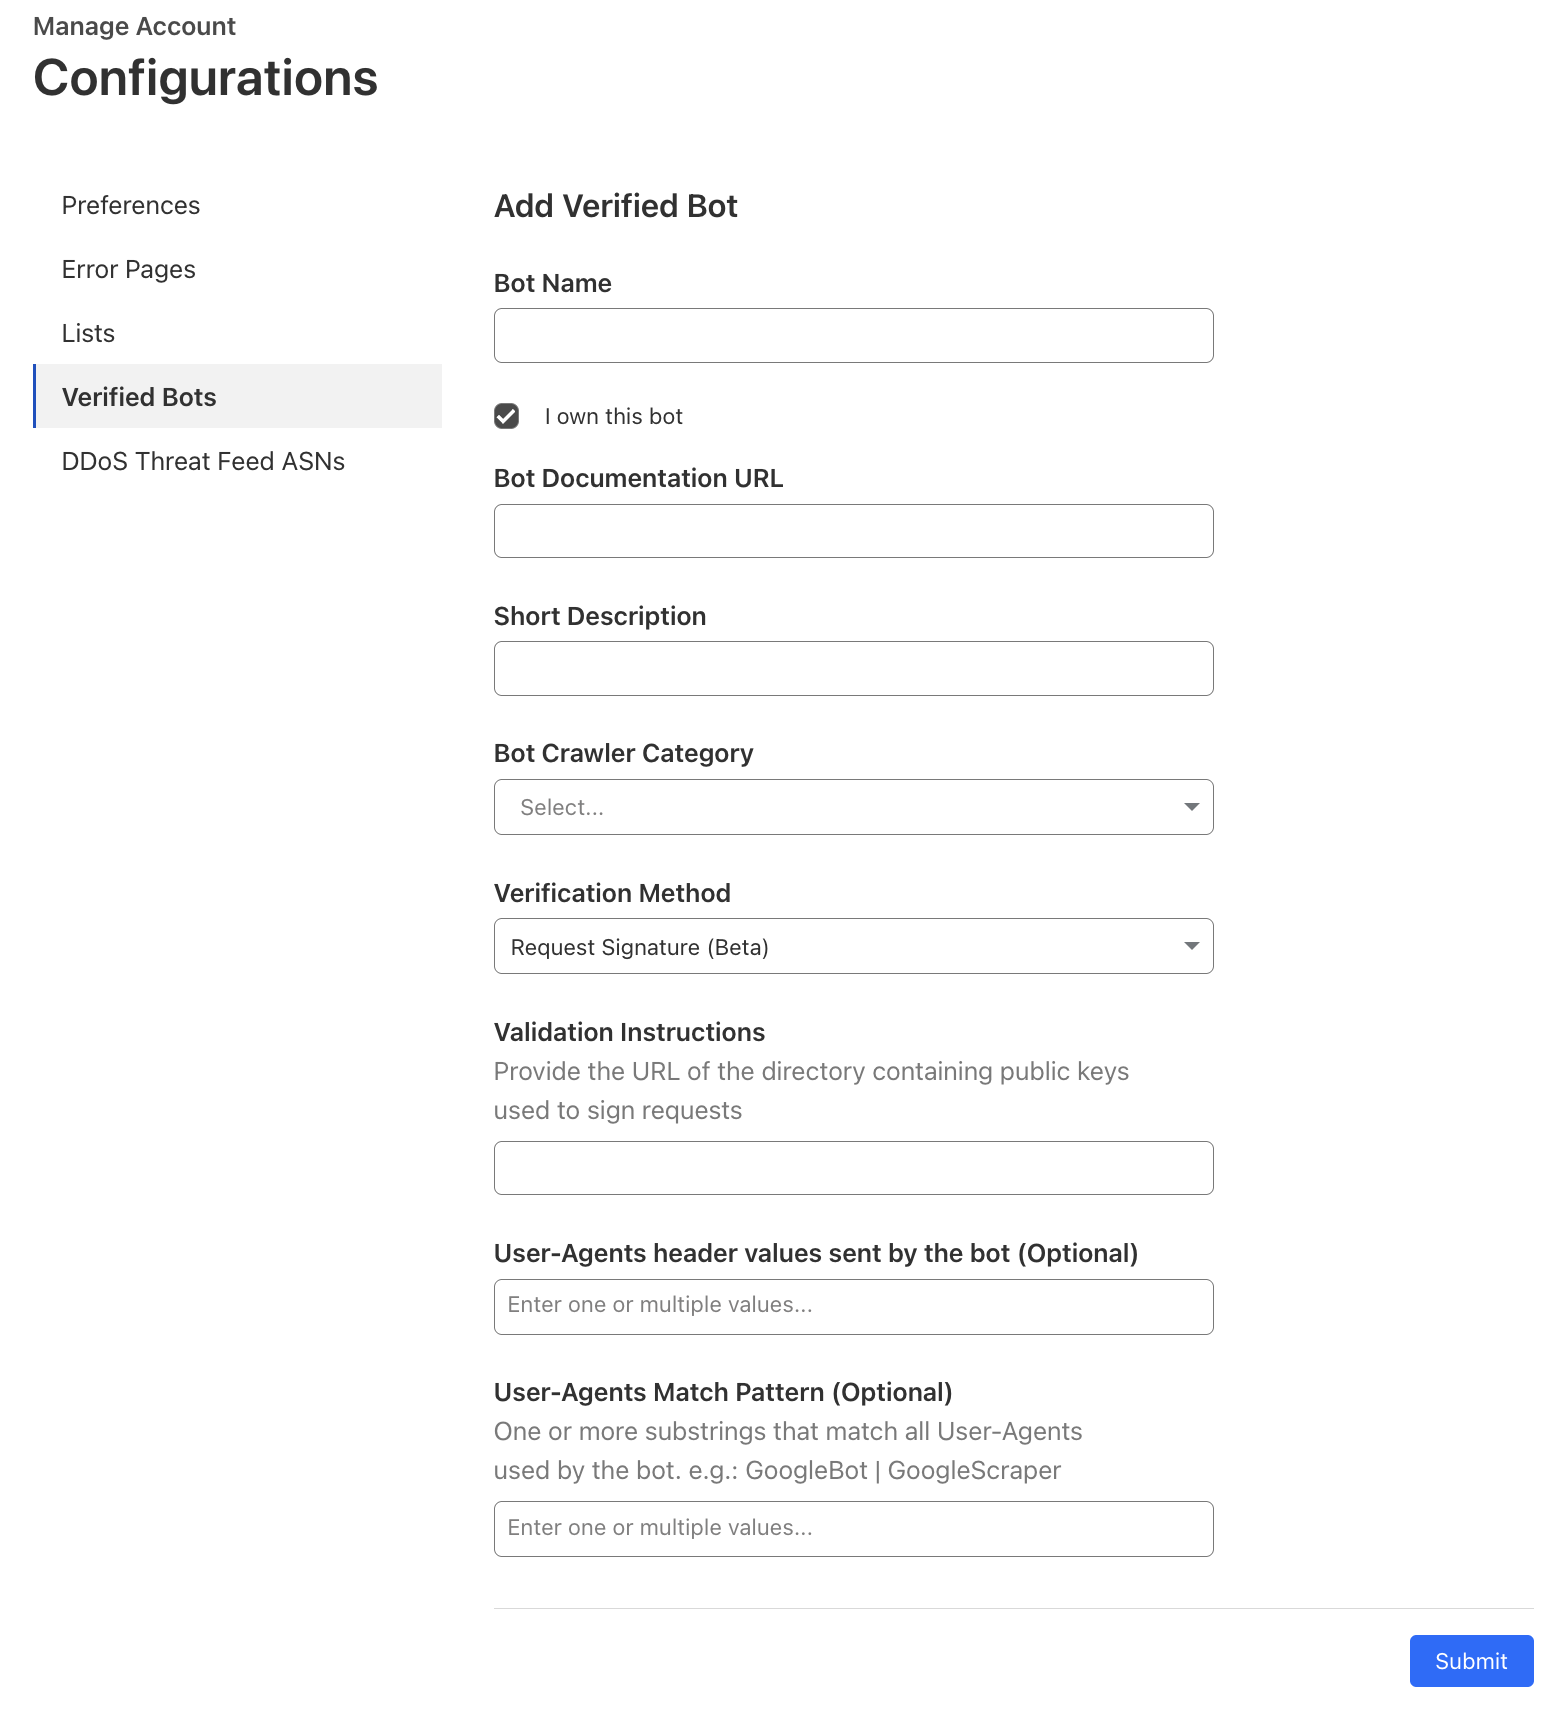
Imagine you’re a bot operator looking to submit your bot to BotBase. Where on the dashboard would you look for such a submission form? Previously, the form lived under Manage Account → Configurations, which tied the bot clearly to your account, but didn’t acknowledge its connection to the bots ecosystem.
Starting today, the bot submission experience has a home next to the rest of your bot and trust tools: Protect & Connect → Application Security → BotBase (new!). All customers can access this today directly from the Cloudflare dashboard.
Here, we’ve split BotBase for Operators by use case:
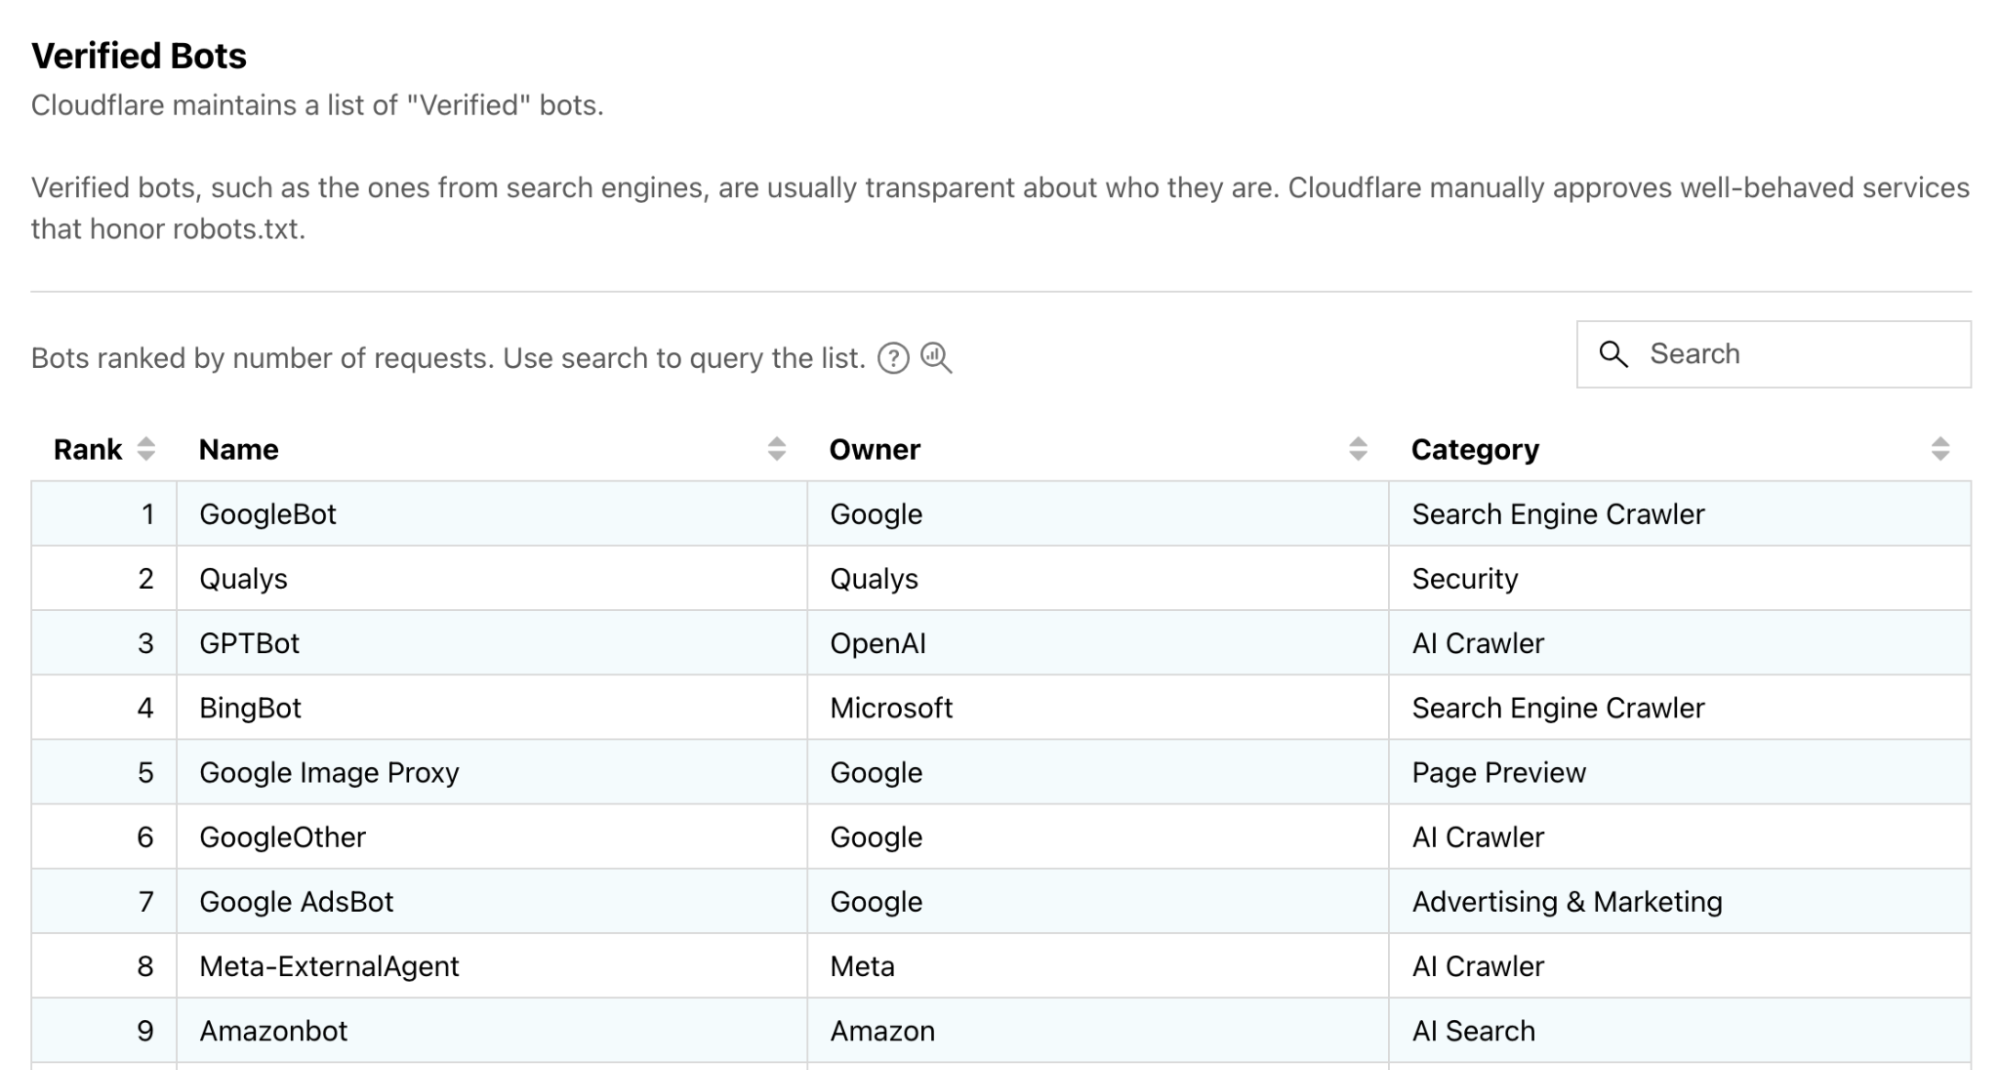
Bots directory — browse, search, and filter the bots Cloudflare already tracks (the same catalogue you can explore on Cloudflare Radar).
Submission form — submit a new bot.
Submission history — track everything you have submitted.
Finding BotBase solves the "where" problem. The "what happens next" problem is the one that we’ve heard is deeply important to bot operators, so we’ll cover that in the rest of this post.
See where your submission stands
We spoke to many bot operators, and the resounding feedback was this: submitting a bot feels like a black box. You fill in the form, press submit, and wait, with no way to tell whether anything happened next.
Now, the Submission history tab shows every bot submitted from your account, each with a clear status:
Waiting for review — we have received your submission and it is in our queue.
Accepted — we have reviewed it and your bot is now tracked in the directory.
Rejected — something in the submission needs to change. We tell you why, with steps you can act on, so you can fix it and resubmit.
Open any submission to see its full details. If it was rejected, you will see the reason why. If it was accepted but we adjusted how your bot is classified, you will see what we changed.
Previously, operators would need to email support just to ask whether their bot got reviewed or to check on their submission's progress. That's exactly the gap we’re closing with this new tab.
Today, the submission form is no longer a black box. Every operator can now view the record of every bot they've submitted starting from today’s launch, with a status you can check anytime. We also provide a way to filter “My bots,” from the Bots directory screen, so you can see all bots that have been submitted under the account with which you’re currently logged in.
Keep your bot's information up to date
A bot's identification details can change over time. You might redesign your website and end up hosting your IP list at a new endpoint. Or you might move from an IP allowlist to signing your traffic with Web Bot Auth, and need your entry to match. Before today, the only way to reflect either change was to fill out the whole form again and submit a brand-new entry. Now, you can edit a submission you have already made.
You can also cancel a submission that is still waiting for review.
We encourage every operator to keep their bot's information current. Accurate details are a key component of how a bot earns and keeps Verified status, which increasingly determines whether sites across Cloudflare's network can easily allow it based on its behavior. Of course, it is ultimately up to the individual site owner to decide what traffic is allowed and what is not.
A submission form built on an updated, pragmatic taxonomy
Picture a bot. Maybe it only crawls pages to build a search index. Maybe it also acts on a user's behalf, or pulls in data for something else entirely. How it uses what it reads matters just as much as what it does.
The new intake form asks you to describe your bot the way it actually behaves. It follows the same behavior and content use model we introduced on July 1, so instead of squeezing your bot into a single label, you now tell us three things.
First, what your bot does. Maybe it only does one thing, like indexing pages for search. Maybe it's an agent acting on a user's behalf, or it collects data, trains models, or supports SEO tools. You can select every behavior that applies, not just the closest match.
Second, how it uses what it reads. A crawler that skims a page for a search snippet is not the same as one that stores that page to train a model. You tell us the level of content use your bot needs, using the same Content Signals model website owners already use to set their own rules. For example, a site's robots.txt might read Content-Signal: search=yes, ai-train=no, use=reference, telling every crawler it's fine to index the page for search and keep a reference, but not to train a model on it. Your bot's content-use declaration is what gets checked against exactly that kind of preference.
Third, who's actually running it. If you operate your bot yourself, straight from your own infrastructure, like a search engine crawling the web to build its own index, that's direct. If you run a platform other companies build on, carrying their traffic without being the one who decided to send it, that's an intermediary. Picture a general-purpose AI assistant fetching a page because someone typed a question into a different company's app built on that assistant's API: the assistant operator runs the infrastructure, but it was someone else's product that decided to send the request. (You can read more about these classifications here.)
That's the full picture: what your bot does, how it treats what it reads, and who's behind it, described as it actually is instead of squeezed into one label. The clearer that picture, the more accurately website owners can decide how to treat your bot.
Faster, more consistent review
Operators also asked for faster reviews. We hear you on this, too.
The number of new bots submitted each year has grown sharply — increasing about 7 times in volume since 2023 — and reviewing every one of them by hand doesn't scale at that pace. Until now, every submission followed the same fully manual path: someone on our team checks it against an internal rubric and makes a judgment call. That kind of review is thorough, but it doesn't scale.
We rebuilt that process to run automatically. Your bot runs through a series of checks — is it a duplicate of one we already track, is your user-agent pattern specific enough to identify your bot without overlapping one that's already registered, and, most importantly, does your claimed verification method actually hold up? We fetch your IP list, confirm your reverse DNS, or validate your Web Bot Auth signature automatically, instead of a person doing it by hand. If everything checks out, your bot can be tracked right away. If something needs a closer look, it's routed to our team with the specific reason already flagged, instead of landing as a blank entry in a queue.
For operators, that means most submissions move faster than before.
Submit your bot today
To join hundreds of bots in BotBase who declare their behavior and content use, and be part of an ecosystem where website owners and bot operators can coexist:
Go to Protect & Connect → Application Security → BotBase in the Cloudflare dashboard.
Open the Submission form and declare your bot: who operates it, what it does, how it uses content, and how it proves its identity.
Submit. Your submission appears in Submission history as Waiting for review.
What's next
This launch is about visibility; there's more coming. Here are our guiding goals:
Visibility, targeted by this launch. This gives operators the ability to see, understand, and edit submissions.
Ownership and observability, being targeted soon. This gives operators the ability to claim bot ownership, manage its live directory entry, and better understand how websites are treating their bot.
Conversation, a longer-term goal. This would open a more sustainable way for bot operators to ask websites to be let in if they can show they provide value rather than harm.
Our vision is to keep expanding BotBase so operators can understand exactly how their bot is treated and get guidance on how to crawl the web more politely, turning a one-way submission into an ongoing relationship.
BotBase started as a directory for website owners. It is becoming a place where bot operators take part in the ecosystem, understand where they stand, and keep their information accurate. If you run a bot, submit it and tell us what you need next. We are building the operator side alongside the operators who use it.
We’re constantly building for the different goals of our customers. Some customers want to optimize for discovery, while others want to protect their content with the strictest security policy. Among these differing policies, there are multiple ways to mitigate bot traffic. Some mechanisms simply state your preference, assuming best intent from crawlers, and other approaches actually lock down content by outright blocking with a Bot Management solution.
We recognize that it's cumbersome to maintain multiple layers of protection on your website. For example, there are cases in which your robots.txt states that a crawler is Disallowed from accessing your website, while your enforcement rules actually don’t block that crawler. When your stated preferences and your enforced rules disagree, some crawlers treat it as a basis to disregard your preferences or try to bypass your enforced rules.
A couple of years ago, Cloudflare announced an easier way to disallow AI training on your website by tackling two of these layers: a managed value of robots.txt that told a fixed list of major Training crawlers not to train on your content, along with edge-enforced blocks to Training crawlers. On July 1, 2026, we launched easier options to manage different kinds of AI traffic use cases. You can say what you want to do about Search, Agent, and Training traffic on your website.
We're announcing Bot Preference Sync, available to all customers from the Free tier to Enterprise. Bot Preference Sync reflects what you've set in your AI bot configuration by updating corresponding preferences to your robots.txt, and it can be turned on or off at any time. No more static file for one use case: we'll help you tailor your robots.txt to reflect what you’ve already configured for different AI bot categories.
New questions facing the Internet
For years, the most pressing question in this space was: "Is my content being used to train AI models without my permission?" It's an important question, and it isn't going away. Alongside this, the questions we increasingly hear are about discoverability and engagement. How do I show up when someone asks an AI assistant something my site can answer? How much of my traffic is coming from AI crawlers versus real people? What content is actually driving referrals, and what is it worth?
The answers differ by business model. Discoverability and engagement are key, top-of-mind issues for any businesses trying to thrive on the modern web, but the funnels for these are different: an e-commerce store may want everything crawled and trained on, so its products surface when a shopper asks a chatbot for "the best sofa for a small apartment." A publisher that monetizes pages with ads may want the opposite: stay in the search index that sends readers to the page, but keep its articles out of model training and, crucially, be able to verify that its content really wasn't used without permission.
There's no single right answer, which is exactly the point. Your controls should reflect your strategy, which is why we've been building tools to give you visibility and choice at every layer. Bot Preference Sync ties these together, so the preference you set is the preference you publish.
The call for Transparency
On July 1, 2026, we made the case that mixed-use crawlers, or “bots that blend search, agent use, and training behind a single user agent,” put site owners at a disadvantage precisely because they make it hard to separate what you want from what you don't. That's still true, and our position on Transparency for site owners hasn't changed.
But there’s more than one way to approach Transparency. We want to reward the operators who are clear about their identity and how they are using the data they crawl. For purposes of bot Verification, the owners of bots that perform both Search and Training will need to provide additional information in order to not be blocked when “Disallow Training” is set. Those requirements are:
The bot must respect, via any mechanism, a “no training” preference in robots.txt
They give site owners a way to opt out of AI summaries.
They provide URL-level visibility into which pages were made available for training, as well metrics on search results, so you can see how your content was used for search and for training.
They can show publicly that Disallowing Training does not hurt your traditional search results.
Bots of leading AI models and service providers that meet these criteria are tracked publicly in the AI bot transparency section in Cloudflare Radar, which includes examples in which best practices are honored, as well as when they are not. Crawlers that don't provide Transparency will not get the benefit of the doubt — they're still blocked when you disallow training. In other words, this is a way of making Transparency the price of admission.
Introducing Bot Preference Sync
Bot Preference Sync is a new feature that keeps your robots.txt reflecting the AI bot preferences you've already set for Search, Agent, and Training on the Cloudflare zone-level dashboard. If a site owner already has a robots.txt file, the contents added by Bot Preference Sync will be prepended to the existing material, so any existing Disallow directives are maintained.
Instead of a site owner maintaining a separate static file, Cloudflare generates or updates your robots.txt based on your configuration, so what you say to the world and what you enforce at the edge are kept in sync.
For Search and Agent, the three options we announced on July 1 remain: Allow, Block on pages that serve ads, or Block everywhere. For Training, we’re refining the option to stop your content being used for training models with the Disallow option:
Disallow: a "no training" preference is written to your robots.txt, so that cooperating mixed-use crawlers who take the extra Transparency step can still access your content for search indexing, since they’re allowing site owners to directly verify how their data is used. Cooperating crawlers honor the preferences in robots.txt, and your Search visibility for cooperating crawlers is unaffected.
Let’s take the example below, in which someone has configured their AI bot policy to say “Allow Search, Allow Agents, Disallow Training.”
Since this example site has Bot Preference Sync on, their robots.txt would prepend something like the following (which has been shortened and anonymized for the sake of the example):
We’ll use bots that we track in BotBase to periodically update the list of bots that is added to robots.txt when you choose to Block or Disallow a given category. The Verified bots that are classified as Search, Agent, and Training can be viewed at any time in our public bots directory.
For all new customers, Bot Preference Sync will be on by default, to make it easier to manage blocks and preferences that reflect the same policy. For existing customers who are using the legacy managed robots.txt feature, we'll prompt you to review and confirm your preferences to transition to the new Bot Preference Sync upon its upcoming launch.
Some customers may want or need to be more hands-on in stating their preferences, for example, if they have a special arrangement with a given company to which they want to grant an exception. Because Bot Preference Sync is designed to tackle policy decisions made category-wide rather than case-by-case, it will not directly read from individual custom rules with more complex logic. Customers with a more fine-tuned security policy always have the option to turn off the sync that sets group policies, and tailor their file to match their custom policy.
We’re also making a change that allows publishers or ad-supported sites to have a different default from other site owners. We’ve created a default to make it easier for publishing sites that rely on ads and expect them to be reserved for human visitors. At the time of onboarding, such customers can select the option, “I monetize from pages with ads on this domain", which will set Training to Disallow as the default. (Customers have the choice to change this setting at any time.) This way, you stay in search while keeping your content out of model training.
For the non-publisher case, new customers will not have any blocks or disallows added by default when they onboard a domain: the choice is up to the customer. You can choose if you want to block Search or Agent or Training at any point, but the starting point will not add any blocks on your behalf.
What's next?
Bot Preference Sync will be available to all customers, on every plan, in the coming week. Keep an eye on our changelog for availability, and watch your dashboard (and inbox) for the prompt to confirm your preferences!
This is one step in a longer effort. We'll keep working with the large bot operators to make sure we're not compromising on familiar challenges (like training without consent) nor emerging questions (like discoverability and engagement). Beneath it all is our effort to promote greater Transparency and control for site owners.
The Internet isn’t a single lane of traffic. For a long time, the rule of thumb in web security was that bots are bad, while humans are good. Of course, we’re far past this generalization. Humans can be fraudulent, and bots can be helpful at different levels. Site owners actively want some automated traffic to interact with our sites to make the Internet functional and discoverable.
To complicate things further, the line between "human" and "bot" is blurring more and more. Now, we have a type of “hybrid” traffic where a single session shifts from human to agentic and back again. (Think of a user browsing a store, and then handing off the checkout process to an automated shopping assistant.)
So, how do website owners manage this kind of complexity? What matters here is assessing behaviors. Is this behavior abusive? Malicious? What’s the risk presented here, and can I trust this visitor based on their actions? Solving this requires moving beyond static, point-in-time checks. It requires analyzing continuous behaviors to evaluate Trust.
In this post, we’ll share an inside look into the strategy of the Web Integrity & Trust team (covering the bots and fraud problem spaces) around detecting and analyzing good and bad behaviors, providing tools to help site owners tackle emerging challenges in the shifting Agentic Internet. We’ll also share findings around agentic traffic since the launch of Precursor, and a simulation where you can see how your own cursor movements would be assessed as human or bot — plus some exciting launch updates to expect in the near future.
Defining Risk and Trust
Let’s talk about the distinction between Risk and Trust, the way we discuss it within the teams at Cloudflare who work in bot detection. These are often viewed as polar opposites of a continuum. At Cloudflare, we look at them as independent, but reciprocal, values. Trust is the essential ingredient in making informed decisions on what to do about your traffic.
Risk is how likely something like a request or action is to be harmful, and it’s often ephemeral. Trust, however, is built up over time, and it’s based on reputation.
We can illustrate this with an example from real life: say that you’re enjoying some evening television at home, when suddenly, you hear the doorbell being rung repeatedly. Besides being annoying, this behavior is strange. Frantic doorbell rings late at night are alarming.
You check through your door camera and see that the person ringing your doorbell is your best friend who lives next door. Of course, you trust your best friend, and we’d bet you would let them in.
In this example, it wouldn’t be enough for you to say, “Reject anyone who rings my doorbell at night” or “Reject anyone who rings my doorbell more than 10 times.” Again, Trust is the essential ingredient.
Going back to traffic on the Internet, the strategy as we build products in the bots and fraud space focuses on building an entire ecosystem based on Trust. And our goal is to provide the incentives and primitives for site owners to use to incentivize behavior that makes the Internet safer for everyone: starting with blocking malicious activity at the bottom, to encouraging participation in a safer Internet at the top.
Good behaviors, rooted in transparency
Starting at the top: what counts as good behavior? We can draw clear examples from the Verified bots and agents within BotBase. Last month, we announced an updated pragmatic taxonomy for the good bots we track in our system, boiling down the definition of “Verified” to two things: 1) you declare yourself honestly, and 2) you don’t abuse the trust you’ve earned.
Transparency between a site owner and a bot operator allows for a symbiotic relationship: site owners can note what behaviors and data uses they want to allow on their websites, and bot operators can be granted access more easily. The transparency allows for Trust in the relationship; if you have nothing to hide, declaring who you are should reduce friction from the sites who want to allow your behaviors.
BotBase is not meant to only make declarations of “who is good”. It is intended to be a directory of all known bots and agents, and provide the facts. Compared to our previous Bots Directory, which only included known good bots, BotBase is also capable of tracking less-than-good bots and agents. Why? Because our systems track and validate behavior for known good actors, meaning we have the tools to identify when these expectations aren’t met. If you abuse trust on the Cloudflare network, you should not be easily allowed, so you will be unverified.
Bad behaviors: blatant, stealthy, and everything in between
A few weeks ago, we announced Precursor, a continuous client-side system to detect even subtly inhuman bot traffic that can fly under the radar when assessing network signals alone. When a customer enables Precursor, the JavaScript detection is CDN-injected, so it doesn’t require sitting at the computer and figuring out where or how to rerun these detections. What's more, Precursor evaluates user behavior continuously throughout the session, so no more free hall passes for abusive traffic that found a way to pass client and browser-side checks just once.
Applying our Risk and Trust framework to these client-side detections, we can point out that CAPTCHAs or one-time hurdles are Risk-based, meaning they lack context. On the other hand, verification using behavioral tells is Trust-based, since it can capture more context clues from the full user session. Precursor is the tool for us to analyze this behavior. To sum it up, Precursor is so powerful because it:
Provides Trust-based detection over the entire user session.
Drives up the cost for bot developers to replicate human behavior over a multipage timeline.
By making it economically disadvantageous for bot developers to outrun these detections, we win the adversarial game.
Now, what have we learned since we’ve launched? Looking at just a 24-hour period at the time of writing this blog, we can see 206 million Precursor evaluation events, across 73,438 zones on the Cloudflare network.
We can see patterns in the data that reveal things that we had suspected when launching the detection, but can now validate across tens of thousands of domains:
Suspicious behavior often happens mid-session, which point-in-time detection wouldn’t catch.
Behavior often shifts from human to agentic and back over a session. In these cases, it’s important to understand the intent so that site owners don’t block user flows that they actually want.
This highlights the importance of a bot classification system that allows website owners to handle traffic by use case, purpose, and data use. This is precisely why we prioritized taxonomy updates for BotBase.
For those curious to learn more on how Precursor actually works, we shared a sneak peek — how the signals we analyze showed us that to err is human — in our announcement blog post. Today, we’re going a step further: giving anyone on the Internet an interactive demo simulating how Precursor would trace your cursor movements.
Precursor Traceis live now, sharing how we’d assess your cursor movements using (part of) Precursor’s detection mechanism. Here, you can see whether you’re accelerating or correcting yourself, the rhythm and texture of your cursor movement, and more — all things you’ve probably never thought about as a real human being interacting with a computer. Try it out!
Adaptive Intelligence is coming soon
Cloudflare’s bot detection engines can produce different outcomes when assessing if a given request is automated or not. For requests that are deemed to be automated, the assessment can be 1) definitely automated, based on proven, deterministic methods or fingerprints of bots, or 2) likely automated, based on predictive scoring from Cloudflare’s Bots ML.
Historically, Bots ML has been updated in versions, meaning we announced each new model version as a product launch. This pacing doesn’t work when bots adapt on the scale of hours or even minutes.
Adaptive Intelligence, a completely new detection engine, is different from anything we’ve built before in the Bots ML space. The model itself is adaptive. It has learned from everything we’ve seen in the past, but more importantly, it will continue to learn and self-adjust based on what it sees. Adaptive Intelligence will upgrade itself based on a wide range of traffic patterns we identify, from good to bad behaviors, and customers will no longer need to upgrade to a formal new model version to have the latest predictive bot detections working for them.
All Bot Management customers will have access to Adaptive Intelligence in the near future — stay tuned for the launch announcement coming soon.
Moving beyond determinism to influence bot behavior
So far, we’ve focused on Cloudflare’s side of things: strategy, detection, and taxonomy. All of this allows Cloudflare to equip website owners with the tools they need to set the traffic policies they want on their sites. Zooming in on the website owner side, we want to take this chance to discuss some advanced mitigations that allow website owners themselves to influence bot behavior.
With more blatant mitigation techniques, we face something that we’ve nicknamed the “Bot Antibiotic Problem.” Always sending bots a deterministic response (like a 403 block) makes it easy for a malicious developer bot to probe, observe, and reverse-engineer your defenses.
We know this, so we’re designing mitigations specifically made for throttling bots — with different approaches for malicious bots vs. benign bots. We can break them down into three approaches:
Approach 1: Unpredictability and Random Actions. Applying random responses (between block, challenge, or allow) to suspected automated traffic breaks a bot's automated retry logic and fingerprinting.
Approach 2: AI Labyrinth, a defensive response that traps unauthorized bots in an endless maze of AI-generated web pages. You can waste malicious bots' compute and crawl budgets by using misdirection. Site owners will be given three options within AI Labyrinth, depending on their preference:
Maze: Generates an endless web of linked pages for bots to follow.
Summary: Feeds crawlers an LLM-generated summary of a page that looks real but is entirely useless as AI training data.
Poison: Serves deliberately fake content (like fake prices or inventory) to a bot, polluting the data it collects for AI training.
Approach 3: Queuing for Good Bots. Not all agentic traffic is bad; queuing manages throughput for legitimate automated traffic (like user-directed shopping agents) without denying them service entirely.
These advanced, bot-specific mitigations are set to roll out closer towards the end of the year, and will be available for the website owner to choose how strict they want their mitigations to be.
We also know that a great defense is a predictive one — one that self-learns and course-corrects without needing multiple security experts on a call to reactively set a fix that accounts for the latest stealth attack. This might look like having a system of “disposable” rules, in which the ruleset is dynamic in nature. This is by design: if attacks constantly evolve, the defenses should, too. That’s why we’re working to keep both detections and mitigations a step ahead.
Establish the Trust ecosystem that works for you
Anyone and everyone can take steps to define how automated agents interact with their infrastructure.
By moving away from static, point-in-time checks and embracing continuous trust evaluation, we reduce the game of whack-a-mole with bot operators. If you’re not already using Cloudflare’s bot detection, check it out and establish the Trust ecosystem that works for you.
Today, it is difficult for AI agents to try out new APIs. They often have to navigate through a login page designed for humans and not agents, contact a human to add a payment method, generate an API key, and then figure out how to call the API.
This flow is very difficult for agents for two reasons: Agents do not have a stable identifier to sign up for an API, and they do not have a native way to pay for APIs. Because they lack these things, they often struggle to onboard onto software, which limits the growth of agentic commerce. AI agents often give up on these tasks entirely, kicking registration, payment methods, and API key generation back to humans. This makes it very difficult for agents to try out and compare many APIs.
To solve this, we’ve created Cloudflare Wallets. Starting today, you can claim a Cloudflare Wallet handle for your account, which will provide a unique username to help you better connect with merchants. Soon, you will be able to set up and use your Cloudflare Wallet to pay for APIs and content.
Earlier this month, we announced the Monetization Gateway to help Cloudflare customers get paid for their websites and applications. Monetization Gateway will support micropayments using the x402 protocol, which allows for payments to be attached to HTTP requests. These micropayments will be able to pay for uses ranging from AI inference to data to content. If you want to pay or get paid for services behind Monetization Gateway and other x402-compatible endpoints, you’ll need a wallet.
Cloudflare Wallets will allow you to store stablecoins, purchase services, and receive funds across the web. Each account with a wallet will also be able to create Virtual Wallets for its agents to enable them to buy APIs, MCP Tools, content, and more. You will be able to define guardrails for your Virtual Wallets (such as an allowance, an allow list, and a maximum transaction size) to help your agent spend money safely from your account. This will allow your agent to try out many APIs with low friction and managed risk. Wallet users will have the option to share their Cloudflare Wallet handles, which will give them a stable identity when interacting with merchants.
Building the two-sided agentic market
Cloudflare’s Monetization Gateway will allow eligible Cloudflare customers to sell their resources (such as content or APIs) headlessly to agentic buyers. But for that market to truly develop, agents need more tools to buy from merchants in a machine-native way. Wallets will add another tool to Cloudflare’s Agents SDK, enabling AI agents to easily purchase necessary APIs and content using micropayments.
There will be two types of Cloudflare Wallets: Account Wallets and Virtual Wallets.
Account Wallets are designed for humans who are owners and users of Cloudflare accounts. They will be able to add funds, delegate spend to virtual wallets managed by agents, and remove funds as needed.
Virtual Wallets, by contrast, are designed for agents and operate via API keys. Within a Virtual Wallet, an agent will be able to spend funds according to its permissions. Its maximum spend will be capped by the limit set by the owner of the Account Wallet. This framework gives agents freedom to act on behalf of users without constant manual approval while limiting an agent’s ability to overspend.
The freedom to explore
Virtual Wallets are exciting because they will allow agents to do what they’re best at: explore dozens or hundreds of services and find the best one for a particular use case. Stablecoin micropayments via x402 will make it simple to try an API without an account, allowing agents to test new options with little friction. The spending caps on Virtual Wallets are designed so that humans can let agents explore autonomously within safe spending limits. These limits may seem like constraints, but counterintuitively they give agents more freedom. If an agent is responsible for $10, you can worry less about its spending than if it is responsible for $1,000. If an API only costs a few cents to try, then $10 is more than sufficient to pursue and evaluate many options.
Once you or your agent has picked an API to use, policies set by you in your Account Wallet will act as cost controls for Virtual Wallets. Want to give every employee a $100 per week budget for AI inference? Simply provision an Account Wallet with the right balance and create Virtual Wallets for each employee with that rule. Anyone who exceeds the limits on their Virtual Wallet will be able to request a manual override from a human who is authorized to make changes to the Account Wallet.
We want to make it easy for Account Wallets to set flexible yet firm spending policies that do not require daily, active monitoring. When something anomalous happens, such as unexpectedly fast spending, a human will be able to review and confirm whether everything is operating as intended. If the spend was intentional, then the administrator of the Account Wallet will be able to raise the limit or approve a one-time injection of funds. If the spend was unintentional, then the spending policies for adding funds to virtual wallets did their job by imposing caps.
We are working to make it as easy as possible to fund and use these wallets. We will start with simple ways to onramp and offramp funds within supported geographies, with self-funding via stablecoins available as an alternative for eligible users. The Internet will not shift completely overnight, but with a majority of traffic on the web now being driven by bots, we are excited to give agents and merchants first-class tools for agentic commerce.
Beyond payments alone
Allowing humans to delegate authority to agents to easily buy and sell services is a helpful starting point. But this delegation is not always obvious to the merchants as they interact with agents. Today, if an agent comes to your website, you may know little about them as a user, despite the fact that the agent is acting on behalf of an individual or an organization. This lack of attribution challenges many traditional web business models. It’s easy to give a one-week free trial or sign-up credits to a human or an organization. It’s hard to give these same perks to an agent that lacks a stable identity and when one human can spin up dozens of agents under their control.
We solve this problem by linking wallets to a Cloudflare account via cloudflare.pay. cloudflare.pay will allow agents to optionally identify themselves, since their identity is a delegate of the account. A research agent could live at research.example.cloudflare.pay, allowing merchants to know that it is an agent from a particular organization. This approach will permit agents to maintain consistent and persistent identities, making the experience better for all parties. It will be completely optional for agents to choose to declare their identity or not, and it will be up to businesses to decide whether they want to prioritize transacting with known agents.
Agent identifiers should be human-readable
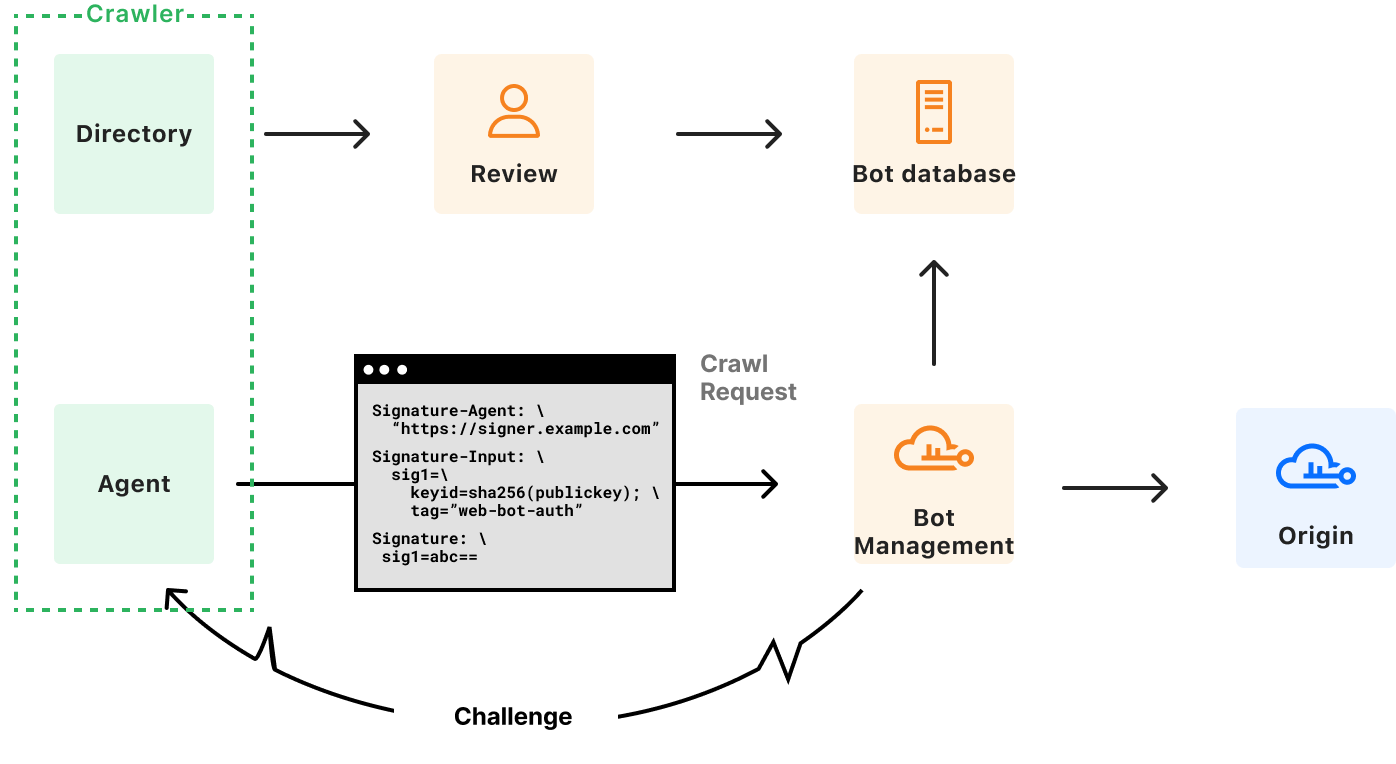
We believe that the approach to dealing with agents will look like the approach to dealing with VPNs: If someone is unidentified, they are not inherently untrustworthy, but they need to prove themselves more. This is why we have Turnstile and other initiatives to detect bots within Bot Management. Our identity primitive will build on top of this prior work. For example, Web Bot Auth already allows agents to register their identity via a keypair. IDs attached to Cloudflare Wallets allow this keypair to become human-readable.
We know that agentic identity standards are changing quickly, which is why we wanted to keep our approach simple. We are proposing a human-readable identifier for a not-very-readable keypair, similar to the URL and IP-address pairings used in DNS. We are not trying to define a particular schema or other verification system. We only want to make identity simple to remember and easy to declare. As schemas to enrich agentic identity develop through the x402 Foundation’s initiatives, we will seek to adopt them and intend to encourage others to do the same.
The future of agentic commerce
At Cloudflare, we want to offer all the building blocks for agentic commerce to succeed. Monetization Gateway will offer a way for sellers to get paid without setting up traditional payment infrastructure. Wallets will offer a way for buyers to pay headlessly via agents. Identity will allow merchants to communicate with buyers who identify themselves or enforce identification requirements.
All of these building blocks will create a headless marketplace for the Internet. If you are excited about this and want to participate, you can claim your handle now. We’re excited to see what you build and monetize.
One year ago, we declared the first Content Independence Day, and we gave website owners the means to take back control of their content. The deal between crawlers and website owners that had held up for 30 years — we crawl you, and you get referrals — was no longer true. AI was taking everything and sending back nothing, presenting an existential threat to website owners. And so we launched a one-click “Block AI Bots” option, along with a Pay-Per-Crawl marketplace.
A lot has changed in a year. Last July, conversations around “AI bots” centered around blocking AI training without compensation, pointing to the win–lose deal where content was used for model training with no value driven back to the website owner. But a desire for more nuance has emerged: Content owners still want to be able to protect their content, and they should be compensated for the original content that they work hard to create, curate, and share. We also know that locking down content isn’t a one-size-fits-all solution; website owners want more options than resorting to “block all automation, every time.”
If you run a small site, the problem isn’t just that someone could train models on your content — it’s that nobody can find you in the first place. So you have to make a Faustian bargain: either show up in search and let AI train on you, or risk losing discoverability. This unfairly advantages incumbent search providers if they use the same bots for both search and training; and this unfair advantage incentivizes new players to be evasive as they try to close the competitive gap.
Now, AI can be anything
Today, AI can be in anything. Google search has changed from being sorted by AI to being a full answer engine that answers your question directly on the results page. And Google is not unique in this position — this is the direction in which “search” is moving.
We could debate the cutoff for what qualifies as “AI” today, just to find that the standard changes tomorrow. So, instead of defining a bot primarily as “AI” or not, our updated approach to classification will ask deeper questions about bot or agent behavior: What are they doing on my site? What are they storing? And how will they reshare my content?
A pragmatic taxonomy
To address these questions, we need a more nuanced view — a pragmatic taxonomy that aligns with the AI use cases our customers care about. So we are opening the discussion beyond AI training alone and focusing on three AI use cases that we want all customers to be able to manage:
Search: any behavior that collects or indexes your content, so it can answer questions about it later. The key is that Search is proactively building a database of your site to later respond to queries with. Site owners should expect to get referral traffic or other equitable compensation as a result.
Agent: automatedbehavior that is acting, usually in real time, on a person’s behalf, to get something done right now. This includes chat fetch bots (e.g., ChatGPT-User) and browser-use agents (e.g., Gemini or Claude driving Chrome). The key is that it visits your web application in order to complete a job, and often there’s a human waiting on the other end.
Training: a crawler taking your content to train or fine-tune a model. The key is that your data is permanently absorbed into the underlying architecture of the AI to improve its capabilities.
Many popular crawlers on the web fall into one of the classifications above; some fall into multiple. We classify plenty of other behaviors beyond the three above — including ads verification, feed fetching, and agentic transactions (more on this below). But we believe it should be simple for all website owners to manage access for these three AI-centered use cases. We believe that bot operators should separate their crawlers because that creates more transparency for website owners: allowing them to better understand why a given crawler is visiting them, as well as to better manage the access they extend to that crawler. If a company runs automation that builds Search indexes, acts as an Agent, and collects data to Train their models, then we strongly encourage that company to separate the automation into three separate crawlers.
We want a classification system that is scalable and representative of the world of automated traffic as it evolves. Tracking a bot’s purposes is nothing new, but our new taxonomy involves a few updates that better represent the state of bot traffic today. Most notably, we want to recognize that bots that have multiple purposes should be tracked with all purposes, not just one of them.
New options to manage AI traffic
We want to provide more options for managing different kinds of AI traffic, to all website owners on the Cloudflare network.
The managed preset to “Block AI bots” that we’ve announced in the past included single-purpose bots that crawled data for model training, as shown below:
Screenshot of the existing setting to manage AI bot traffic on July 1, 2025.
But not all AI use is the same, and we want our customers to have the controls they need. So, we’re launching the ability to manage AI traffic based on three major use cases: Search, Agent, and Training crawlers. With these new options, our customers can more finely tune how they manage AI bot traffic — including customers on our Free tier.
Screenshot of the new options to manage AI bot traffic on July 1, 2026.
Setting new defaults
On September 15, 2026, we’ll be setting new defaultsfor each of these three classifications. For all new domains onboarding to Cloudflare, the categories of Training and Agent will be blocked by default on the pages that display ads, while Search will remain allowed by default.
An ad is a signal that a website owner meant for a person to land there and see it — something monetizable that fuels the business. So, on those pages, we treat human attention as the end goal, and keep away the bots that may prevent this attention (i.e., Training and Agent bots). On the other hand, Search is the behavior that most naturally funnels back visitors, and we believe it’s in the interest of most site owners to allow this.
Another change that will apply on September 15 is that multi-purpose crawlers (specifically those that combine Search with Training) will be allowed/blocked according to all of their behaviors, in line with our call for transparency for website owners. Since the defaults will be enforced by the most restrictive applicable rules, multi-purpose crawlers such as Googlebot, Applebot, and BingBot will be blocked by customers who have selected to block Training (either through the new options to manage AI traffic, or through the legacy Block AI bots service).
Of course, customer choice is paramount: if a website owner wants to opt out of these new default configurations, they can easily mark this in their Security settings any time leading up to September 15, which will confirm that they want no changes on Training crawlers that also crawl for Search purposes. We’ll also continue to notify customers of the upcoming change to defaults as we approach September 15 to ensure that customers who want to choose settings different from the defaults have the opportunity to do so.
BotBase: a new visibility plane for Enterprise customers
We’re also excited to launch a major visibility update as a new feature of Enterprise Bot Management. As Cloudflare’s directory of tracked bots has grown, so has the desire to manage these bots in sensible groupings and to understand more detail about a particular bot.
Introducing BotBase. BotBase is our new database tracking all known bots, including Verified bots and agents. This database provides a comprehensive, searchable view of our entire directory of bots, directly on the Cloudflare dashboard. We’re tackling visibility first, but, later this year, we’ll expand BotBase to provide a direct control center for known automated content on your website.
With this new view, Enterprise Bot Management customers can see the full catalogue of all Verified bots/agents and where they are classified in this updated taxonomy — a view we’ve never shown dynamically on the Cloudflare dashboard before. Customers who want to precisely target a specific bot can also easily filter for all traffic from this bot, plus copy the detection ID to use in Security rules. All of this is now live within a dedicated page, which can be accessed through the Bot Management configuration card.
As we built BotBase, we wanted to account for all of the pieces of information that would allow us to build scalable, powerful insights from bot to bot. One of these pieces is a cornerstone for our updated taxonomy, which is based on what a bot may do on your site — its behavior. We separate these classifications as shared below, and each bot is classified with one or more of these behaviors.
Bot classification
Behaviors and uses
Search
Crawling to scan your site to help it appear in search engine results
Agent
User-directed agents visiting a page on behalf of a human
Training
Crawling to train or fine-tune models
Transact
Checkout actions on behalf of users
Data Collection
Includes price scraping, competitive intelligence gathering, and third-party analytics
Security Testing
Includes vulnerability scanning and penetration testing
SEO
SEO crawling, site auditing, accessibility checks
Ads Verification
Ad placement verification, ad fraud detection
Social / Link Preview
Link previews for social platforms and messaging apps
Feed Fetching
Includes RSS readers, podcast aggregators, and news feed bots
Monitoring & Operations
Includes uptime monitoring, webhooks, and health checks
Bold italicized rows indicate the new configurable options that are available to all customers.
How does a crawler use my content?
Another piece of information we’ve heard is important to our customers is a bot’s content use — what a bot may keep and reshare after it has crawled your content. To address this, we are building capabilities for Bot Management customers to select and block based on the “content use.” This setting can be set to one of three levels, from least to most permissive:
immediate — interact, but store and reuse nothing
reference (default) — index, excerpt, and link back
full — summarize and reproduce
These values can be combined with bot classifications to express nuanced rules, such as “allow all bots that are used for Search, SEO, and Ads Verification, but only up to the reference use level.” This allows website owners to make decisions in sensible groupings rather than manage individual bot-by-bot rules.
To further support this, starting today, we’re testing a new signal, use, that extends Content Signals and lives in your robots.txt. This extends the three fields of the first version of Content Signals with a fourth, optional field that expresses the same preference as above:
use=immediate
use=reference
use=full
As with all other items listed in the robots.txt file, the values of content use signal a website owner’s preference, rather than issuing blocks directly. We’re now adding support for this extension: all customers who have already enabled managed robots.txt — which prepends the preference to robots.txt that crawling for search is okay, but that crawling for training is not — will now have the additional preference of use=reference added to their robots.txt.
# Cloudflare Managed content with original Content Signals

User-agent: *
Content-Signal: search=yes,ai-train=no
Allow: /
The contents of Cloudflare managed robots.txt with the original Content Signals values.
# Cloudflare Managed content with the new content-use signal

User-agent: *
Content-Signal: search=yes,ai-train=no,use=reference
Allow: /
The contents of Cloudflare managed robots.txt with the added parameter.
We’re also starting to track content uses for every bot in BotBase, and when we discover a bot abusing these signals, it will lose the “Verified” status, resulting in it no longer being allowed. Today, bots that reproduce in full cannot have the Verified status.
What does it mean for a bot to be Verified?
Speaking of “Verified,” the definition of Verified is being updated to reflect the upcoming changes to default allow and block baselines. Previously, all Verified bots were allowed by default, which was reflected in our basic Bot Fight Mode offering to block unwanted automatic traffic and in our rule templates for Enterprise Bot Management customers.
Starting today, we’re adjusting this to add nuance: non-verified bots are still default blocked, but we are no longer viewing Verified as “default allowed.” Now, the Verified label makes a bot allowable with its relevant category, meaning the allowed category (e.g., allowing Search) will determine what is allowed to access a website.
To balance this change, we’re opening up the process of becoming a Verified bot, and making it more transparent, too. To “Verify” a bot, a bot operator needs to show two things: that you represent yourself honestly, and you don’t abuse the access that honesty earns. And to make this easier on bot operators, we’re currently building management tools for bot operators to better ensure they are accurately represented by Cloudflare’s classification system (to be announced in the near future).
A preview screenshot of the upcoming platform built directly for bot operators who are part of or want to be a part of BotBase, the next generation of the Cloudflare Bots Directory.
Experimenting with transitive trust
One more piece: The bot (or agent) at your door increasingly isn’t run by the company that built it. A platform like Cloudflare’s Developer Platform runs automations for thousands of different operators at once, ranging from enterprises to a developer you’ve never heard of. You might trust Stripe, but you don’t necessarily trust everyone who wired Stripe’s tools into a weekend project.
We call the case of (site owner → bot owning company → end user) a matter of transitive trust, and we’re proposing to utilize the existing Forwarded header as defined in RFC 7239 that rides along with the request and allows “proxy components to disclose information lost in the proxying process.”
This is similar to what X-Forwarded-For does for IP addresses, or X-Forwarded-Host does to preserve the original Host header. So when a website owner says, “Allow this operator,” that preference will hold, whether the operator comes to you directly or through three layers of intermediaries that are trusted. More details can be found in our documentation, with a brief example to show the format below.
Forwarded: for="openai"
Adding the extension with content-use discussed above, the header addition would look something like the below, specifying how the operator says they will use the content they access:
Forwarded: for="openai";use="reference"
This also lines up the incentive model we want to foster. Losing trusted status across the more than 20% of web domains that sit behind Cloudflare is a deterrent with teeth. Trust becomes something you can carry with you, and something you can lose.
However, as bot traffic blends with human traffic, it’s possible that this system of transitive trust doesn’t carry beyond the users who can afford to be identifiable. The measures we are proposing today help to convey trust, but they won’t fit the entire web for all time. Small sources of traffic need privacy, and companies that want to preserve their own privacy commitments should be able to explore fair building blocks for the future of an agentic Internet, such as private rate limiting.
Set your terms today
These are small changes that move in the same direction: site owners get more control over who uses their content, and how. We believe the new defaults we discussed today and will soon implement are ones that encourage transparency and are more reflective of where the world is going.
Of course, the ebbs and flows of the web will continue shifting under us, and we’ll keep adjusting with it. But the direction won’t change, because it’s the one Cloudflare started with: a web ecosystem built around trust. Where the people who make things can decide how they’re used — and one where being honest about what you do earns you more access, not less.
These new options to manage AI traffic are live now, and can be configured by all existing customers in their zone Settings. Not on Cloudflare yet? Start for free to set the traffic controls that you want today.
Search drives most experiences on the web. It’s how we get things done, and how nearly everything on the web gets found — the creators, the merchants, the answer to whatever you just typed into a box. For nearly 30 years, that discovery journey ran on a simple bargain: let a search engine crawl your content, and it sends you visitors. You turned those visitors into a business — through ads, subscriptions, or just the audience itself. Being discoverable and getting paid were the same thing. A year ago, on the first Content Independence Day, we drew a line to defend that bargain in the AI era. But a line in the sand was only a first step. Since then, the prevalence of AI search in consumers’ lives has only accelerated as more than 50% of traffic online is non-human. The threat is no longer a handful of training crawlers you can block; it’s search itself being rebuilt around AI answers.
Today’s answer engines read your page and hand the user a summary, so the visit — and the revenue that depended on it — isn’t needed. We see it firsthand, and independent research backs it up: a 2025 Pew Research Center study found that when Google shows an AI summary, users clicked on a traditional search result link just 8% of the time (about half as often as when there’s no summary) and clicked a link inside the summary only 1% of the time. That leaves our customers in a bind: opt out of AI and be hard to find, or opt in and deliver significant value to users while seeing increasingly little in return. Our customers want to be found and compensated for the value they provide, and right now they’re forced to choose.
Today, we’ve announced new bot options to help our customers better control who can access their site and what they can do with it. But blocking was only step one: saying “no” protects content without rebuilding the business models that sustain it. So, it’s time to start building the new economic model of the Internet, starting with search.
Rebuilding the bargain
Transparency and control are the foundation, but more is needed. In 2025, we laid out our foundation via a set of responsible AI bot principles: bots should be transparent about who they are and what they’re for, respect site owners’ choices, and act in good faith. Our tools hold bots to that bar. But enforcing good bot behavior doesn’t make AI search any better for the people relying on it, and it doesn’t send a dollar back to the creator whose work made the answer possible. We can do more than help the web say “no”; we can help rebuild what it says “yes” to.
So today, we’re announcing two initiatives that move from defense to offense and start putting both halves of that old bargain back together.
Make AI search smarter: Byusing the signals we see across our global network, like what’s fresh, what’s high quality, and what’s actually changed, we can help answer engines surface the most relevant content and reduce unwanted crawling. People searching get better answers, while costs are reduced for both AI companies and site owners if webpages are only recrawled when they’ve changed.
Pay creators for the value they provide: When your work is used to answer someone’s question, you should be rewarded instead of just being scraped for free. And you should be able to see what’s being used and what people are asking. This should be a real revenue stream, and an incentive to keep producing original content worth finding.
Making search smarter
Today we’re launching a research program to make AI search smarter and stop our customers footing the bill for crawls that produce nothing new.
More than 20% of the web sits behind Cloudflare’s network, which gives us a unique perspective. We can tell which pages have genuinely changed and which ones people and agents are flocking to. Through this program, we will explore using signals our customers have chosen to share about the freshness of their content, and we will combine those with our own insight into traffic flows, both human and bot. For answer engines, that’s a roadmap to high-quality content. For our customers, it provides a view of what users are actually asking, and how their content shows up in AI results. The aim is to measure two things: how much these signals help answer engines to surface fresher, higher-quality content, and how much unnecessary crawling they cut out.
That second benefit, cutting unnecessary crawling, is bigger than it sounds. Cloudflare data suggests that more than 50% of crawl traffic from good bots goes to re-fetching pages that haven’t changed — and that number is likely to climb as crawl volumes do. A signal that just says “nothing’s changed here” lets a crawler skip the trip. That saves the answer engine compute. More importantly, it saves site owners from serving and paying for requests they never needed to.
The program is neutral by design: our goal is to make it work for every answer engine willing to play fair. It’s limited to search. We aren’t sharing any content, and nothing is used to train foundation models. We intend to publish what we learn, including the benefits to site owners such as better content discoverability and reduced server strain. We plan to make the capability broadly available later this year and reduce unnecessary crawling across our network.
From Pay Per Crawl to Pay Per Use
Last year we launched Pay Per Crawl so publishers could charge AI companies for crawling their content. It was a real start, but crawling is a crude measure of value. A single page might be crawled once and then cited in thousands of answers, or crawled over and over and never used at all. Creators want to be paid fairly for the value they provide.
So we’re starting to shape Pay Per Crawl into Pay Per Use. We’re running experiments with top AI companies, like Ceramic.ai and You.com, and the arrangement is straightforward: organizations can bring their payment models and easily scale them to content owners across the Cloudflare network.
Ceramic has built what it calls a “pay-per-query” model, so publishers who opt in can be paid when their content appears in Ceramic’s search results. This means payment is designed to follow the value the work delivers rather than the number of times a crawler happens to fetch it.
“To scale the future of AI search, we need a partner with massive reach and a shared commitment to transparency and fair compensation,” saysAnna Patterson, founder and CEO of Ceramic.ai. “Cloudflare allows us to easily and programmatically scale our operations. By bringing our pay-per-query model to their network, we ensure millions of content owners can seamlessly opt in to be compensated every single time their content appears in our search results.”
In addition to compensation, content owners participating in the Cloudflare/Ceramic program will unlock new reporting to help with answer engine optimization (AEO). Customers can finally see the top queries leading to their content appearing in search results, the specific webpage and snippet, their average search result ranking position, and more. This is the first of many products we’ll be launching to help our customers with discoverability.
This is just one emerging approach. Another comes from You.com: agents can pay on demand for a specific piece of premium content they need, without any upfront commitment. New payment models from AI providers are being tested (e.g., Pay per Query, Pay per Result, etc.) and we have the infrastructure to support them all.
We want to be honest that this is an experiment. There’s a lot to learn, including exactly how this holds up at the scale of the Internet. We’ll work that out with our partners and our customers as we go, and share what we learn. But the goal is clear: AI search companies get fresher, better-grounded answers, and the customers whose work makes the answers possible get paid when they help. Cloudflare’s job in all of this is to provide the infrastructure layer that makes this market flourish.
We think this is a more natural fit for where the economics of search are heading. The old, human web optimized search to save time — providing excerpts, ten blue links, and a click. The agentic Internet is different: an agent can read fast and search continuously. Search is becoming something an agent does dozens of times to answer a single question, closer to a utility than a destination. In that world, the unit that matters isn’t the crawl or the click. It’s the outcome. Pricing the outcome, and paying the people who made it possible, is how the web continues to thrive.
The headline we want to earn
A year ago on Content Independence Day, the headline was a default ‘no’: AI can’t crawl without compensation. This year, our focus is on giving our users more products and controls to say ‘yes’ and bring more benefits with it.
Today’s announcements are just the beginning. Cloudflare’s research project is designed to see if our signals produce better results with less crawling. Pay Per Use is a promising direction we’ll experiment with alongside partners who believe that content creators deserve fair compensation for their work. This is how the last 30 years of the web got built too: somebody runs the pilot that turns “the model is broken” into “here’s the new model,” one experiment at a time. We believe there’s value to our customers to be discoverable in this new agentic era, and to optimize their content for maximum discovery. But they should be able to do this without giving away their most valuable creative assets for free.
The web is changing, and the business models it’s relied on are changing with it. The old Internet was open, neutral, and worth contributing to. We have a rare chance to keep it that way, and to build the business models that fund it in the future. Smarter answers for humans and agents asking the questions. A fair deal for the people whose skill, creativity, and commitment makes the answers worthwhile. That’s how we pursue Cloudflare’s mission: to help build a better Internet.
Happy Content Independence Day!
Building on the open, agent-ready web? If you are interested in learning more about the Ceramic and You programs, please fill out this form. If you’re building an answer engine and want to crawl smarter, we’d love to hear from you too: [email protected].
Today, we are announcing the Cloudflare Monetization Gateway, an engine that will give Cloudflare customers the ability to charge for any asset protected by Cloudflare: web pages, datasets, APIs, or MCP tools.
It will provide a single control plane to manage payment policies and access controls across your applications, while also protecting your origin from high payment volumes by handling payment verification and enforcement at the edge. At launch, payments will settle in stablecoins over x402, the open protocol we are building with a coalition of more than 25 industry leaders via the x402 Foundation.
The evolving business model of the web
For 30 years, the web has run on a simple economic bargain: trading content for human attention. That attention has been monetized through advertising, subscriptions, and e-commerce. This bargain funded the Internet as we know it.
But as agents become the dominant Internet users, the model is breaking. An agent does not look at ads or need to maintain a monthly subscription to all the tools it wants to access. It reads a page or consumes a data feed once, takes what it needs, and moves on. Across the web, AI crawlers already request content anywhere from a hundred to tens of thousands of times for every visitor they send back.
This reality demands a new model: usage-based pricing for everything. If attention and e-commerce are moving from websites to AI harnesses and AI-written software, then agents should pay for the inputs they need — training data, inference content, developer tooling, and API usage. The natural unit of payment for software is the request, the token, or the outcome, not the seat or the month. A few examples of what that could look like:
A few cents per web search, billed per call
\$0.001 base fee plus a \$0.01 per MB charge for an upload endpoint
\$0.99 per resolved support escalation, paid only when the work succeeds
This is the same shift behind paying creators when an answer engine uses their content — a fair exchange of value whenever content or a resource is used, priced on neutral rails built for the purpose. People often envision an agent buying high-priced assets like web domains, but most of what an agent pays for sits upstream of any checkout, and is priced far lower.
Some of the Internet already works this way. Cloud and APIs have been sold by the call and by the hour for years, but only to a known buyer: a user signs up, they are issued an API key, and they incur usage-based metered billing. Content mostly skipped payment and ran on advertising instead. These business models have never been able to serve unverified buyers for sub-cent transactions because the payment rails cost too much and took too long to settle. Below a certain price, collecting the payment cost more than the payment was worth.
Historically, usage-based billing was difficult to implement. Businesses needed to effectively become payments companies, running their own accounting to track internal usage in a robust and auditable way. Tracking this usage required significant overhauls of backend systems. Many instead chose per-seat pricing because it is simpler and frequently more profitable.
Agents flip this dynamic. A single agent can do the work of an entire team around the clock, making a flat one-time fee disconnected from actual consumption. At the same time, an agent can make thousands of micropayments without friction, while asking a person to approve each payment would be impossibly burdensome. Usage-based price points are where agents live and where stablecoin-based micropayments shine. That’s because stablecoins (such as Open USD and USDC) allow buyers to transfer tiny sums across the Internet, incurring negligible fees and settling in less than a second. This is not feasible with other payment rails today.
Here’s where we can help. Cloudflare has spent years building usage-based accounting for our own billing systems and for our customers’ analytics. We can dramatically simplify the implementation of usage-based billing for web-based assets thanks to our position as a proxy layer between buyers and sellers. As shown below, with Cloudflare supporting usage-based billing, the evidence of payment can move into the request itself, and the payment validation and the request paths merge.
And here’s the benefit to you: the metering, the payment exchange, and the settlement move off your origin. What stays with you is what matters — your rules, your prices, and your revenue. You will not need to onboard the buyer or stand up a billing system. You will write a rule and agentic buyers will pay for what they use.
A refresher on x402
Last year on Content Independence Day, we gave site owners one-click control over which AI crawlers could reach their content, and with Pay Per Crawl we let them charge crawlers for it. The Monetization Gateway is the next step: instead of only charging crawlers for content, you will be able to charge any caller for any resource, from an API to data to an MCP tool call, and you will not have to build the payment machinery yourself.
x402 is an open protocol that makes it possible to pay over HTTP, named for the 402 status code it finally puts to use. The x402 exchange is simple: a client requests a payment-gated resource. Instead of serving it, the server responds with 402 Payment Required and a small payload that states the price, the accepted asset, and where to pay. The client pays and repeats the request with proof of payment attached. A facilitator verifies, and the server returns the resource. It all happens inside ordinary HTTP requests and responses, with no redirect to a checkout page and no separate payment API to call. Settlement happens peer-to-peer, so any funds that a buyer sends to a seller are directly deposited to the seller’s wallet. We are designing the Monetization Gateway to keep payment overhead low and are aiming for sub-second payment settlement.
Two properties make x402 a good fit for machine payments. The payment amounts can be small, down to fractions of a cent, because the protocol adds almost no overhead. And the buyer needs no account with the seller, because the payment itself is the credential. x402 is rail agnostic, but it is a natural fit for stablecoins, which can settle in under a second for a fraction of a cent with zero chargebacks.
What the Monetization Gateway does
The Monetization Gateway will provide a flexible payment rules API that will allow you to express exactly when you want a caller to pay to access your digital resources.
Here’s how it will work. Tokens, APIs, MCP tool calls, and data already flow through that path. You will decide, as precisely as you want, which of that traffic has to pay. And you will be able to enforce your decisions by writing expressions, similar to expressions that you already write for other Cloudflare rules, in a simple, dedicated product API. The Monetization Gateway will scale with Cloudflare’s global network across 330+ cities, which means that the x402 handshake will occur in close proximity to your buyer. This will reduce request latency and protect your origin.
A few examples of planned capabilities:
Charge for specific REST verbs: Require payment on calls to a specific route, for example $0.01 for every GET or POST request to /api/premium/*.
Variable pricing: Charge variable amounts for tasks of varying complexity, for example, image generation might charge any amount up to $2, depending on the compute used.
Charge only unauthenticated callers: Intercept HTTP 401 “Unauthorized” responses from your origin and return 402 “Payment Required” instead with pricing and payment instructions.
When a request matches, the Monetization Gateway will verify payment before letting it through. You will be able to set these rules in the dashboard, or manage them as code through the Cloudflare API and Terraform, so a paid endpoint is just another part of your infrastructure config.
The Monetization Gateway will initially allow users to require buyers to pay for services and resources in stablecoins. Sellers will be able to use the stablecoins they accumulate for their own transactions or redeem the stablecoins for equivalent fiat currency in their bank account. Using the Monetization Gateway offers a way to increase the addressable market for your products. With the Gateway, agents can request your resource, be told the price, pay, and get the response. No signup, no API key, no prior relationship required. You will decide how much you need to know about that buyer, and you will have the flexibility to require agents to authenticate with Web Bot Auth and apply usage-based pricing against accounts they already hold.
Where we see this going
The Monetization Gateway will turn the request into a payment and give Cloudflare customers new revenue opportunities, but where this goes is far bigger.
An agent is software that acts autonomously on a user’s behalf, and agents are starting to act on their own. Soon they will carry wallets and buy what they need without a person in the loop: a dataset, an API call, a tool, a block of compute. Some of those resources will be free, and some will require proof of who the agent is and who it acts for, through verified agent identity. Many will require both an identity and a payment, and Cloudflare is one of the few places that will be able to settle all of it inside a single request, by verifying the agent, applying the rule, and checking the payment before the origin ever sees the call. The agent becomes the primary buyer on the Internet, and the request becomes the transaction.
There is an enormous amount of value moving across the Internet today that goes unmonetized or undermonetized, not because no one would pay for it, but because the tools to charge for it have never existed. Every useful API call, every answer, every tool invocation an agent makes has value, and almost none of it is paid for today. That is the opportunity in front of us, and it is what the Monetization Gateway will unlock.
This is what we are building toward: an agent-first Internet with Internet-scale settlement built in. Where the people who make something worth paying for get paid by the software that uses it, automatically. And where the smallest new API can reach the same buyers, on the same terms, as the largest company on the web, and the independent creator is paid by the large language models that use their work. That is the next business model of the Internet, and we are building to power it.
Sign up for our waitlist
The Monetization Gateway waitlist is open now for Cloudflare customers. If you’re interested in monetizing your web page, dataset, API, or MCP tool with usage-based pricing, please join our early access list.
Earlier this week, the UK’s Competition and Markets Authority (CMA) opened its consultation on a package of proposed conduct requirements for Google. The consultation invites comments on the proposed requirements before the CMA imposes any final measures. These new rules aim to address the lack of choice and transparency that publishers (broadly defined as “any party that makes content available on the web”) face over how Google uses search to fuel its generative AI services and features. These are the first consultations on conduct requirements launched under the digital markets competition regime in the UK.
We welcome the CMA’s recognition that publishers need a fairer deal and believe the proposed rules are a step into the right direction. Publishers should be entitled to have access to tools that enable them to control the inclusion of their content in generative AI services, and AI companies should have a level playing field on which to compete.
But we believe the CMA has not gone far enough and should do more to safeguard the UK’s creative sector and foster healthy competition in the market for generative and agentic AI.
CMA designation of Google as having Strategic Market Status
In January 2025, the UK’s regulatory landscape underwent a significant legal shift with the implementation of the Digital Markets, Competition and Consumers Act 2024 (DMCC). Rather than relying on antitrust investigations to address risks to competition, the CMA can now designate firms as having Strategic Market Status (SMS) when they hold substantial, entrenched market power. This designation allows for targeted CMA interventions in digital markets, such as imposing detailed conduct requirements, to improve competition.
In October 2025, the CMA designated Google as having SMS in general search and search advertising, given its 90 percent share of the search market in the UK. Crucially, this designation encompasses AI Overviews and AI Mode, with the CMA now having the authority to impose conduct requirements on Google’s search ecosystem. Final requirements imposed by the CMA are not merely suggestions but legally enforceable rules that can relate specifically to AI crawling with significant sanctions to ensure Google operates fairly.
Publishers need a meaningful way to opt out of Google’s use of their content for generative AI
The CMA’s designation could not be more timely. As we’ve said before, we are indisputably in a time when the Internet needs clear “rules of the road” for AI crawling behavior.
As the CMA rightly states, “publishers have no realistic option but to allow their content to be crawled for Google’s general search because of the market power Google holds in general search. However, Google currently uses that content in both its search generative AI features and in its broader generative AI services.”
In other words: the same content that Google scrapes for search indexing is also used for inference/grounding purposes, like AI Overviews and AI Mode, which rely on fetching live information from the Internet in response to real-time user queries. And that creates a big problem for publishers—and for competition.
Because publishers cannot afford to disallow or block Googlebot, Google’s search crawler, on their website, they have to accept that their content will be used in generative AI applications such as AI Overviews and AI Mode within Google Search that return very little, if any, traffic to their websites. This undermines the ad-supported business models that have sustained digital publishing for decades, given the critical role of Google Search in driving human traffic to online advertising. It also means that Google’s generative AI applications enter into direct competition with publishers by reproducing their content, most often without attribution or compensation.
Publishers’ reluctance to block Google because of its dominance in search gives Google an unfair competitive advantage in the market for generative and agentic AI. Unlike other AI bot operators, Google can use its search crawler to gather data for a variety of AI functions with little fear that its access will be restricted. It has minimal incentive to pay publishers for that data, which it is already getting for free.
This prevents the emergence of a well-functioning marketplace where AI developers negotiate fair value for content. Instead, other AI companies are disincentivized from coming to the table, as they are structurally disadvantaged by a system that allows one dominant player to bypass compensation entirely. As the CMA itself recognizes, “[b]y not providing sufficient control over how this content is used, Google can limit the ability of publishers to monetise their content, while accessing content for AI-generated results in a way that its competitors cannot match”.
Google’s advantage
Cloudflare data validates the concern about Google’s competitive advantage. Based on our data, Googlebot sees significantly more Internet content than its closest peers.
Over an observed period of two months, Googlebot successfully accessed individual pages almost two times more than ClaudeBot and GPTBot, three times more than Meta-ExternalAgent, and more than three times more than Bingbot. The difference was even more extreme for other popular AI crawlers: for instance, Googlebot saw 167 times more unique pages than PerplexityBot. Out of the sampled unique URLs using our network that we observed over the last two months, Googlebot crawled roughly 8%.
In rounded multiple terms, Googlebot sees:
vs. ~1.70x the amount of unique URLs seen by ClaudeBot;
vs. ~1.76x the amount of unique URLs seen by GPTBot;
vs. ~2.99x the amount of unique URLs by Meta-ExternalAgent;
vs. ~3.26x the amount of unique URLs seen by Bingbot;
vs. ~5.09x the amount of unique URLs seen by Amazonbot;
vs. ~14.87x the amount of unique URLs seen by Applebot;
vs. ~23.73x the amount of unique URLs seen by Bytespider;
vs. ~166.98x the amount of unique URLs seen by PerplexityBot;
vs. ~714.48x the amount of unique URLs seen by CCBot; and
vs: ~1801.97x the amount of unique URLs seen by archive.org_bot.
Googlebot also stands out in other Cloudflare datasets.
Even though it ranks as the most active bot by overall traffic, publishers are far less likely to disallow or block Googlebot in their robots.txt file compared to other crawlers. This is likely due to its importance in driving human traffic to their content—and, as a result, ad revenue—through search.
As shown below, almost no website explicitly disallows the dual-purpose Googlebot in full, reflecting how important this bot is to driving traffic via search referrals. (Note that partial disallows often impact certain parts of a website that are irrelevant for search engine optimization, or SEO, such as login endpoints.)
Robots.txt merely allows the expression of crawling preferences; it is not an enforcement mechanism. Publishers rely on “good bots” to comply. To manage crawler access to their sites more effectively—and independently of a given bot’s compliance—publishers can set up a Web Application Firewall (WAF) with specific rules, technically preventing undesired crawlers from accessing their sites. Following the same logic as with robots.txt above, we would expect websites to block mostly other AI crawlers but not Googlebot.
Indeed, when comparing the numbers for customers using AI Crawl Control, Cloudflare’s own AI crawler blocking tool that is integrated in our Application Security suite, between July 2025 and January 2026, one can see that the number of websites actively blocking other popular AI crawlers (e.g., GPTBot, Claudebot), was nearly seven times as high as the number of websites that blocked Googlebot and Bingbot. (Like Googlebot, Bingbot combines search and AI crawling and drives traffic to these sites, but given its small market share in search, its impact is less significant.)
So we agree with the CMA on the problem statement. But how can publishers be enabled to effectively opt out of Google using their content for its generative AI applications? We share the CMA’s conclusion that “in order to be able to make meaningful decisions about how Google uses their Search Content, (…) publishers need the ability effectively to opt their Search Content out of both Google’s search generative AI features and Google’s broader generative AI services.”
But we’re concerned that the CMA’s proposal is insufficient.
CMA’s proposed publisher conduct requirements
On January 28, 2026, the CMA published four sets of proposed conduct requirements for Google, including conduct requirements related to publishers. According to the CMA, the proposed publisher rules are designed to address concerns that publishers (1) lack sufficient choice over how Google uses their content in its AI-generated responses, (2) have limited transparency into Google’s use of that content, and (3) do not get effective attribution for Google’s use of their content. The CMA recognized the importance of these concerns because of the role that Google search plays in finding content online.
The conduct requirements would mandate Google grant publishers “meaningful and effective” control over whether their content is used for AI features, like AI Overviews. Google would be prohibited from taking any action that negatively impacts the effectiveness of those control options, such as intentionally downranking the content in search.
To support informed decisionmaking, the CMA proposal also requires Google to increase transparency, by publishing clear documentation on how it uses crawled content for generative AI and on exactly what its various publisher controls cover in practice. Finally, the proposal would require Google to ensure effective attribution of publisher content and to provide publishers with detailed, disaggregated engagement data—including specific metrics for impressions, clicks, and “click quality”—to help them evaluate the commercial value of allowing their content to be used in AI-generated search summaries.
The CMA’s proposed remedies are insufficient
Although we support the CMA’s efforts to improve options for publishers, we are concerned that the proposed requirements do not solve the underlying issue of promoting fair, transparent choice over how their content is used by Google. Publishers are effectively forced to use Google’s proprietary opt-out mechanisms, tied specifically to the Google platform and under the conditions set by Google, rather than granting them direct, autonomous control. A framework where the platform dictates the rules, manages the technical controls, and defines the scope of application does not offer “effective control” to content creators or encourage competitive innovation in the market. Instead, it reinforces a state of permanent dependency.
Such a framework also reduces choice for publishers. Creating new opt-out controls makes it impossible for publishers to choose to use external tools to block Googlebot from accessing their content without jeopardizing their appearance in Search results. Instead, under the current proposal, content creators will still have to allow Googlebot to scrape their websites, with no enforcement mechanisms to deploy and limited visibility available if Google does not respect their signalled preferences. Enforcement of these requirements by the CMA, if done properly, will be very onerous, without guarantee that publishers will trust the solution.
In fact, Cloudflare has received feedback from its customers that Google’s current proprietary opt-out mechanisms, including Google-Extended and ‘nosnippet’, have failed to prevent content from being utilized in ways that publishers cannot control. These opt-out tools also do not enable mechanisms for fair compensation for publishers.
More broadly, as reflected in our proposed responsible AI bot principles, we believe that all AI bots should have one distinct purpose and declare it, so that website owners can make clear decisions over who can access their content and why. Unlike its leading competitors, such as OpenAI and Anthropic, Google does not comply with this principle for Googlebot, which is used for multiple purposes (search indexing, AI training, and inference/grounding). Simply requiring Google to develop a new opt-out mechanism would not allow publishers to achieve meaningful control over the use of their content.
The most effective way to give publishers that necessary control is to require Googlebot to be split up into separate crawlers. That way, publishers could allow crawling for traditional search indexing, which they need to attract traffic to their sites, but block access for unwanted use of their content in generative AI services and features.
Requiring crawler separation is the only effective solution
To ensure a fair digital ecosystem, the CMA must instead empower content owners to prevent Google from accessing their data for particular purposes in the first place, rather than relying on Google-managed workarounds after the crawler has already accessed the content for other purposes. That approach also enables creators to set conditions for access to their content.
Although the CMA described crawler separation as an “equally effective intervention”, it ultimately rejected mandating separation based on Google’s input that it would be too onerous. We disagree.
Requiring Google to split up Googlebot by purpose — just like Google already does for its nearly 20 other crawlers — is not only technically feasible, but also a necessary and proportionate remedy that empowers website operators to have the granular control they currently lack, without increasing traffic load from crawlers to their websites (and in fact, perhaps even decreasing it, should they choose to block AI crawling).
To be clear, a crawler separation remedy benefits AI companies, by leveling the playing field between them and Google, in addition to giving UK-based publishers more control over their content. (There has been widespread public support for a crawler separation remedy by Daily Mail Group, the Guardian and the News Media Association.) Mandatory crawler separation is not a disadvantage to Google, nor does it undermine investment in AI. On the contrary, it is a pro-competitive safeguard that prevents Google from leveraging its search monopoly to gain an unfair advantage in the AI market. By decoupling these functions, we ensure that AI development is driven by fair-market competition rather than the exploitation of a single hyperscaler’s dominance.
******
The UK has a unique chance to lead the world in protecting the value of original and high-quality content on the Internet. However, we worry that the current proposals fall short. We would encourage rules that ensure that Google operates under the same conditions for content access as other AI developers, meaningfully restoring agency to publishers and paving the way for new business models promoting content monetization.
Cloudflare remains committed to engaging with the CMA and other partners during upcoming consultations to provide evidence-based data to help shape a final decision on conduct requirements that are targeted, proportional, and effective. The CMA still has an opportunity to ensure that the Internet becomes a fair marketplace for content creators and smaller AI players—not just a select few tech giants.
The Internet is in the midst of one of the most complex transitions in its history: the migration to post-quantum (PQ) cryptography. Making a system safe against quantum attackers isn’t just a matter of replacing elliptic curves and RSA with PQ alternatives, such as ML-KEM and ML-DSA. These algorithms have higher costs than their classical counterparts, making them unsuitable as drop-in replacements in many situations.
Nevertheless, we’re making steady progress on the most important systems. As of this writing, about 50% of TLS connections to Cloudflare’s edge are safe against store-now/harvest-later attacks. Quantum safe authentication is further out, as it will require more significant changes to how certificates work. Nevertheless, this year we’ve taken a major step towards making TLS deployable at scale with PQ certificates.
That said, TLS is only the lowest hanging fruit. There are many more ways we have come to rely on cryptography than key exchange and authentication and which aren’t as easy to migrate. In this blog post, we’ll take a look at Anonymous Credentials (ACs).
ACs solve a common privacy dilemma: how to prove a specific fact (for example that one has had a valid driver’s license for more than three years) without over-sharing personal information (like the place of birth)? Such problems are fundamental to a number of use cases, and ACs may provide the foundation we need to make these applications as private as possible.
Just like for TLS, the central question for ACs is whether there are drop-in, PQ replacements for its classical primitives that will work at the scale required, or will it be necessary to re-engineer the application to mitigate the cost of PQ.
We’ll take a stab at answering this question in this post. We’ll focus primarily on an emerging use case for ACs described in a concurrent post: rate-limiting requests from agentic AI platforms and users. This demanding, high-scale use case is the perfect lens through which to evaluate the practical readiness of today’s post-quantum research. We’ll use it as our guiding problem to measure each cryptographic approach.
We’ll first explore the current landscape of classical AC adoption across the tech industry and the public sector. Then, we’ll discuss what cryptographic researchers are currently looking into on the post-quantum side. Finally, we’ll take a look at what it’ll take to bridge the gap between theory and real-world applications.
While anonymous credentials are only seeing their first real-world deployments in recent years, it is critical to start thinking about the post-quantum challenge concurrently. This isn’t a theoretical, too-soon problem given the store-now decrypt-later threat. If we wait for mass adoption before solving post-quantum anonymous credentials, ACs risk being dead on arrival. Fortunately, our survey of the state of the art shows the field is close to a practical solution. Let’s start by reviewing real-world use-cases of ACs.
Real world (classical) anonymous credentials
In 2026, the European Union is set to launch its digital identity wallet, a system that will allow EU citizens, residents and businesses to digitally attest to their personal attributes. This will enable them, for example, to display their driver’s license on their phone or perform ageverification. Cloudflare’s use cases for ACs are a bit different and revolve around keeping our customers secure by, for example, rate limiting bots and humans as we currently do with Privacy Pass. The EU wallet is a massive undertaking in identity provisioning, and our work operates at a massive scale of traffic processing. Both initiatives are working to solve a shared fundamental problem: allowing an entity to prove a specific attribute about themselves without compromising their privacy by revealing more than they have to.
The EU’s goal is a fully mobile, secure, and user-friendly digital ID. The current technical plan is ambitious, as laid out in the Architecture Reference Framework (ARF). It defines the key privacy goals of unlinkability to guarantee that if a user presents attributes multiple times, the recipients cannot link these separate presentations to conclude that they concern the same user. However, currently proposed solutions fail to achieve this. The framework correctly identifies the core problem: attestations contain unique, fixed elements such as hash values, […], public keys, and signatures that colluding entities could store and compare to track individuals.
In its present form, the ARF’s recommendation to mitigate cross-session linkability is limited-time attestations. The framework acknowledges in the text that this would only partially mitigate Relying Party linkability. An alternative proposal that would mitigate linkability risks are single-use credentials. They are not considered at the moment due to complexity and management overhead. The framework therefore leans on organisational and enforcement measures to deter collusion instead of providing a stronger guarantee backed by cryptography.
This reliance on trust assumptions could become problematic, especially in the sensitive context of digital identity. When asked for feedback, cryptographic researchers agree that the proper solution would be to adopt anonymous credentials. However, this solution presents a long-term challenge. Well-studied methods for anonymous credentials, such as those based on BBS signatures, are vulnerable to quantum computers. While some anonymousschemes are PQ-unlinkable, meaning that user privacy is preserved even when cryptographically relevant quantum computers exist, new credentials could be forged. This may be an attractive target for, say, a nation state actor.
New cryptography also faces deployment challenges: in the EU, only approved cryptographic primitives, as listed in the SOG-IS catalogue, can be used. At the time of writing, this catalogue is limited to established algorithms such as RSA or ECDSA. But when it comes to post-quantum cryptography, SOG-IS is leaving the problem wide open.
The wallet’s first deployment will not be quantum-secure. However, with the transition to post-quantum algorithms being ahead of us, as soon as 2030 for high-risk use cases per the EU roadmap, research in a post-quantum compatible alternative for anonymous credentials is critical. This will encompassstandardizing more cryptography.
Finally, ongoing efforts at the Internet Engineering Task Force (IETF)aimto build a more private Internet by standardizing advanced cryptographic techniques. Active individual drafts (i.e., not yet adopted by a working group), such as Longfellow and Anonymous Credit Tokens (ACT), and adopted drafts like Anonymous Rate-limited Credentials (ARC), propose more flexible multi-show anonymous credentials that incorporate developments over the last several years. At IETF 117 in 2023, post-quantum anonymous credentials and deployable generic anonymous credentials were presented as a research opportunity. Check out our post on rate limiting agents for details.
Before we get into the state-of-the-art for PQ, allow us to try to crystalize a set of requirements for real world applications.
Requirements
Given the diversity of use cases, adoption of ACs will be made easier by the fact that they can be built from a handful of powerful primitives. (More on this in our concurrent post.) As we’ll see in the next section, we don’t yet have drop-in, PQ alternatives for these kinds of primitives. The “building blocks” of PQ ACs are likely to look quite different, and we’re going to know something about what we’re building towards.
For our purposes, we can think of an anonymous credential as a kind of fancy blind signature. What’s that you ask? A blind signature scheme has two phases: issuance, in which the server signs a message chosen by the client; and presentation, in which the client reveals the message and the signature to the server. The scheme should be unlinkable in the sense that the server can’t link any message and signature to the run of the issuance protocol in which it was produced. It should also be unforgeable in the sense that no client can produce a valid signature without interacting with the server.
The key difference between ACs and blind signatures is that, during presentation of an AC, the client only presents part of the message in plaintext; the rest of the message is kept secret. Typically, the message has three components:
Private state, such as a counter that, for example, keeps track of the number of times the credential was presented. The client would prove to the server that the state is “valid”, for example, a counter with value $0 \leq C \leq N$, without revealing $C$. In many situations, it’s desirable to allow the server to update this state upon successful presentation, for example, by decrementing the counter. In the context of rate limiting, this is the number of how many requests are left for a credential.
A random value called the nullifier that is revealed to the server during presentation. In rate-limiting, the nullifier prevents a user from spending a credential with a given state more than once.
Public attributes known to both the client and server that bind the AC to some application context. For example, this might represent the window of time in which the credential is valid (without revealing the exact time it was issued).
Such ACs are well-suited for rate limiting requests made by the client. Here the idea is to prevent the client from making more than some maximum number of requests during the credential’s lifetime. For example, if the presentation limit is 1,000 and the validity window is one hour, then the clients can make up to 0.27 requests/second on average before it gets throttled.
It’s usually desirable to enforce rate limits on a per-origin basis. This means that if the presentation limit is 1,000, then the client can make at most 1,000 requests to any website that can verify the credential. Moreover, it can do so safely, i.e., without breaking unlinkability across these sites.
The current generation of ACs being considered for standardization at IETF are only privately verifiable, meaning the server issuing the credential (the issuer) must share a private key with the server verifying the credential (the origin). This will be sufficient for some deployment scenarios, but many will require public verifiability, where the origin only needs the issuer’s public key. This is possible with BBS-based credentials, for example.
Finally, let us say a few words about round complexity. An AC is round optimal if issuance and presentation both complete in a single HTTP request and response. In our survey of PQ ACs, we found a number of papers that discovered neat tricks that reduce bandwidth (the total number of bits transferred between the client and server) at the cost of additional rounds. However, for use cases like ours, round optimality is an absolute necessity, especially for presentation. Not only do multiple rounds have a high impact on latency, they also make the implementation far more complex.
Within these constraints, our goal is to develop PQ ACs that have as low communication cost (i.e., bandwidth consumption) and runtime as possible in the context of rate-limiting.
“Ideal world” (PQ) anonymous credentials
The academic community has produced a number of promising post-quantum ACs. In our survey of the state of the art, we evaluated several leading schemes, scoring them on their underlying primitives and performance to determine which are truly ready for the Internet. To understand the challenges, it is essential to first grasp the cryptographic building blocks used in ACs today. We’ll now discuss some of the core concepts that frequently appear in the field.
Relevant cryptographic paradigms
Zero-knowledge proofs
Zero-knowledge proofs (ZKPs) are a cryptographic protocol that allows a prover to convince a verifier that a statement is true without revealing the secret information, or witness. ZKPs play a central role in ACs: they allow proving statements of the secret part of the credential’s state without revealing the state itself. This is achieved by transforming the statement into a mathematical representation, such as a set of polynomial equations over a finite field. The prover then generates a proof by performing complex operations on this representation, which can only be completed correctly if they possess the valid witness.
General-purpose ZKP systems, like Scalable Transparent Arguments of Knowledge (STARKs), can prove the integrity of any computation up to a certain size. In a STARK-based system, the computational trace is represented as a set of polynomials. The prover then constructs a proof by evaluating these polynomials and committing to them using cryptographic hash functions. The verifier can then perform a quick probabilistic check on this proof to confirm that the original computation was executed correctly. Since the proof itself is just a collection of hashes and sampled polynomial values, it is secure against quantum computers, providing a statistically sound guarantee that the claimed result is valid.
Cut-and-Choose
Cut-and-choose is a cryptographic technique designed to ensure a prover’s honest behaviour by having a verifier check a random subset of their work. The prover first commits to multiple instances of a computation, after which the verifier randomly chooses a portion to be cut open by revealing the underlying secrets for inspection. If this revealed subset is correct, the verifier gains high statistical confidence that the remaining, un-opened instances are also correct.
This technique is important because while it is a generic tool used to build protocols secure against malicious adversaries, it also serves as a crucial case study. Its security is not trivial; for example, practical attacks on cut-and-choose schemes built with (post-quantum) homomorphic encryption have succeeded by attacking the algebraic structure of the encoding, not the encryption itself. This highlights that even generic constructions must be carefully analyzed in their specific implementation to prevent subtle vulnerabilities and information leaks.
Sigma Protocols
Sigma protocols follow a more structured approach that does not require us to throw away any computations. The three-move protocol starts with a commitment phase where the prover generates some randomness, which is added to the input to generate the commitment, and sends the commitment to the verifier. Then, the verifier challenges the prover with an unpredictable challenge. To finish the proof, the prover provides a response in which they combine the initial randomness with the verifier’s challenge in a way that is only possible if the secret value, such as the solution to a discrete logarithm problem, is known.
Depiction of a Sigma protocol flow, where the prover commits to their witness $w$, the verifier challenges the prover to prove knowledge about $w$, and the prover responds with a mathematical statement that the verifier can either accept or reject.
In practice, the prover and verifier don’t run this interactive protocol. Instead, they make it non-interactive using a technique known as the Fiat-Shamir transformation. The idea is that the prover generates the challenge itself, by deriving it from its own commitment. It may sound a bit odd, but it works quite well. In fact, it’s the basis of signatures like ECDSA and even PQ signatures like ML-DSA.
MPC in the head
Multi-party computation (MPC) is a cryptographic tool that allows multiple parties to jointly compute a function over their inputs without revealing their individual inputs to the other parties. MPC in the Head (MPCitH) is a technique to generate zero-knowledge proofs by simulating a multi-party protocol in the head of the prover.
The prover simulates the state and communication for each virtual party, commits to these simulations, and shows the commitments to the verifier. The verifier then challenges the prover to open a subset of these virtual parties. Since MPC protocols are secure even if a minority of parties are dishonest, revealing this subset doesn’t leak the secret, yet it convinces the verifier that the overall computation was correct.
This paradigm is particularly useful to us because it’s a flexible way to build post-quantum secure ZKPs. MPCitH constructions build their security from symmetric-key primitives (like hash functions). This approach is also transparent, requiring no trusted setup. While STARKs share these post-quantum and transparent properties, MPCitH often offers faster prover times for many computations. Its primary trade-off, however, is that its proofs scale linearly with the size of the circuit to prove, while STARKs are succinct, meaning their proof size grows much slower.
Rejection sampling
When a randomness source is biased or outputs numbers outside the desired range, rejection sampling can correct the distribution. For example, imagine you need a random number between 1 and 10, but your computer only gives you random numbers between 0 and 255. (Indeed, this is the case!) The rejection sampling algorithm calls the RNG until it outputs a number below 11 and above 0:
Calling the generator over and over again may seem a bit wasteful. An efficient implementation can be realized with an eXtendable Output Function (XOF). A XOF takes an input, for example a seed, and computes an arbitrarily-long output. An example is the SHAKE family (part of the SHA3 standard), and the recently proposed round-reduced version of SHAKE called TurboSHAKE.
Let’s imagine you want to have three numbers between 1 and 10. Instead of calling the XOF over and over, you can also ask the XOF for several bytes of output. Since each byte has a probability of 3.52% to be in range, asking the XOF for 174 bytes is enough to have a greater than 99% chance of finding at least three usable numbers. In fact, we can be even smarter than this: 10 fits in four bits, so we can split the output bytes into lower and higher nibbles. The probability of a nibble being in the desired range is now 56.4%:
Rejection sampling by batching queries.
Rejection sampling is a part of many cryptographic primitives, including many we’ll discuss in the schemes we look at below.
Building post-quantum ACs
Classical anonymous credentials (ACs), such as ARC and ACT, are built from algebraic groups- specifically, elliptic curves, which are very efficient. Their security relies on the assumption that certain mathematical problems over these groups are computationally hard. The premise of post-quantum cryptography, however, is that quantum computers can solve these supposedly hard problems. The most intuitive solution is to replace elliptic curves with a post-quantum alternative. In fact, cryptographers have been working on a replacement for a number of years: CSIDH.
This raises the key question: can we simply adapt a scheme like ARC by replacing its elliptic curves with CSIDH? The short answer is no, due to a critical roadblock in constructing the necessary zero-knowledge proofs. While we can, in theory, build the required Sigma protocols or MPC-in-the-Head (MPCitH) proofs from CSIDH, they have a prerequisite that makes them unusable in practice: they require a trusted setup to ensure the prover cannot cheat. This requirement is a non-starter, as no algorithm for performing a trusted setup in CSIDH exists. The trusted setup for sigma protocols can be replaced by a combination of generic techniques from multi-party computation and cut-and-choose protocols, but that adds significant computation cost to the already computationally expensive isogeny operations.
This specific difficulty highlights a more general principle. The high efficiency of classical credentials like ARC is deeply tied to the rich algebraic structure of elliptic curves. Swapping this component for a post-quantum alternative, or moving to generic constructions, fundamentally alters the design and its trade-offs. We must therefore accept that post-quantum anonymous credentials cannot be a simple “lift-and-shift” of today’s schemes. They will require new designs built from different cryptographic primitives, such as lattices or hash functions.
Prefabricated schemes from generic approaches
At Cloudflare, we explored a post-quantum privacy pass construction in 2023 that closely resembles the functionality needed for anonymous credentials. The main result is a generic construction that composes separate, quantum-secure building blocks: a digital signature scheme and a general-purpose ZKP system:
The figure shows a cryptographic protocol divided into two main phases: (1.) Issuance: The user commits to a message (without revealing it) and sends the commitment to the server. The server signs the commitment and returns this signed commitment, which serves as a token. The user verifies the server’s signature. (2.) Redemption: To use the token, the user presents it and constructs a proof. This proof demonstrates they have a valid signature on the commitment and opens the commitment to reveal the original message. If the server validates the proof, the user and server continue (e.g., to access a rate-limited origin).
The main appeal of this modular design is its flexibility. The experimental implementation uses a modified version of the signature ML-DSA signatures and STARKs, but the components can be easily swapped out. The design provides strong, composable security guarantees derived directly from the underlying parts. A significant speedup for the construction came from replacing the hash function SHA3 in ML-DSA with the zero-knowledge friendly Poseidon.
However, the modularity of our post-quantum Privacy Pass construction incurs a significant performance overhead demonstrated in a clear trade-off between proof generation time and size: a fast 300 ms proof generation requires a large 173 kB signature, while a 4.8s proof generation time cuts the size of the signature nearly in half. A balanced parameter set, which serves as a good benchmark for any dedicated solution to beat, took 660 ms to sign and resulted in a 112 kB signature. The implementation is currently a proof of concept, with perhaps some room for optimization. Alternatively, a different signature like FN-DSA could offer speed improvements: while its issuance is more complex, its verification is far more straightforward, boiling down to a simple hash-to-lattice computation and a norm check.
However, while this construction gives a functional baseline, these figures highlight the performance limitations for a real-time rate limiting system, where every millisecond counts. The 660 ms signing time strongly motivates the development of dedicated cryptographic constructions that trade some of the modularity for performance.
Solid structure: Lattices
Lattices are a natural starting point when discussing potential post-quantum AC candidates. NIST standardized ML-DSA and ML-KEM as signature and KEM algorithms, both of which are based on lattices. So, are lattices the answer to post-quantum anonymous credentials?
The answer is a bit nuanced. While explicit anonymous credential schemes from lattices exist, they have shortcomings that prevent real-world deployment: for example, a recent scheme sacrifices round-optimality for smaller communication size, which is unacceptable for a service like Privacy Pass where every second counts. Given that our RTT is 100ms or less for the majority of users, each extra communication round adds tangible latency especially for those on slower Internet connections. When the final credential size is still over 100 kB, the trade-offs are hard to justify. So, our search continues. We expand our horizon by looking into blind signatures and whether we can adapt them for anonymous credentials.
Two-step approach: Hash-and-sign
A prominent paradigm in lattice-based signatures is the hash-and-sign construction. Here, the message is first hashed to a point in the lattice. Then, the signer uses their secret key, a lattice trapdoor, to generate a vector that, when multiplied with the private key, evaluates to the hashed point in the lattice. This is the core mechanism behind signature schemes like FN-DSA.
Adapting hash-and-sign for blind signatures is tricky, since the signer may not learn the message. This introduces a significant security challenge: If the user can request signatures on arbitrary points, they can mount an attack to extract the trapdoor by repeatedly requesting signatures for carefully chosen arbitrary points. These points can be used to reconstruct a short basis, which is equivalent to a key recovery.
The standard defense against this attack is to require the user to prove in zero-knowledge that the point they are asking to be signed is the blinded output of the specified hash function. However, proving hash preimages leads to the same problem as in the generic post-quantum privacy pass paper: proving a conventional hash function (like SHA3) inside a ZKP is computationally expensive and has a large communication complexity.
This difficult trade-off is at the heart of recent academic work. The state-of-the-art paper presents two lattice-based blind signature schemes with small signature sizes of 22 KB for a signature and 48 kB for a privately-verifiable protocol that may be more useful in a setting like anonymous credential. However, this focus on the final signature size comes at the cost of an impractical issuance. The user must provide ZKPs for the correct hash and lattice relations that, by the paper’s own analysis, can add to several hundred kilobytes and take 20 seconds to generate and 10 seconds to verify.
While these results are valuable for advancing the field, this trade-off is a significant barrier for any large-scale, practical system. For our use case, a protocol that increases the final signature size moderately in exchange for a more efficient and lightweight issuance process would be a more suitable and promising direction.
Best of two signatures: Hash-and-sign with aborts
A promising technique for blind signatures combines the hash-and-sign paradigm with Fiat-Shamir with aborts, a method that relies on rejection sampling signatures. In this approach, the signer repeatedly attempts to generate a signature and aborts any result that may leak information about the secret key. This process ensures the final signature is statistically independent of the key and is used in modern signatures like ML-DSA. The Phoenix signature scheme uses hash-and-sign with aborts, where a message is first hashed into the lattice and signed, with rejection sampling employed to break the dependency between the signature and the private key.
Building on this foundation is an anonymous credential scheme for hash-and-sign with aborts. The main improvement over hash-and-sign anonymous credentials is that, instead of proving the validity of a hash, the user commits to their attributes, which avoids costly zero-knowledge proofs.
The scheme is fully implemented and credentials with attribute proofs just under 80 KB and signatures under 7 kB. The scheme takes less than 400 ms for issuance and 500 ms for showing the credential. The protocol also has a lot of features necessary for anonymous credentials, allowing users to prove relations between attributes and request pseudonyms for different instances.
This research presents a compelling step towards real-world deployability by combining state-of-the-art techniques to achieve a much healthier balance between performance and security. While the underlying mathematics are a bit more complex, the scheme is fully implemented and with a proof of knowledge of a signature at 40 kB and a prover time under a second, the scheme stands out as a great contender. However, for practical deployment, these figures would likely need a significant speedup to be usable in real-time systems. An improvement seems plausible, given recent advances in lattice samplers. Though the exact scale we can achieve is unclear. Still, we think it would be worthwhile to nudge the underlying design paradigm a little closer to our use cases.
Do it yourself: MPC-in-the-head
While the lattice-based hash-and-sign with aborts scheme provides one path to post-quantum signatures, an alternative approach is emerging from the MPCitH variant VOLE-in-the-Head (VOLEitH).
This scheme builds on Vector Oblivious Linear Evaluation (VOLE), an interactive protocol where one party’s input vector is processed with another’s secret value delta, creating a correlation. This VOLE correlation is used as a cryptographic commitment to the prover’s input. The system provides a zero-knowledge proof because the prover is bound by this correlation and cannot forge a solution without knowing the secret delta. The verifier, in turn, just has to verify that the final equation holds when the commitment is opened. This system is linearly homomorphic, which means that two commitments can be combined. This property is ideal for the commit-and-prove paradigm, where the prover first commits to the witnesses and then proves the validity of the circuit gate by gate. The primary trade-off is that the proofs are linear in the size of the circuit, but they offer substantially better runtimes. We also use linear-sized proofs for ARC and ACT.
Example of evaluating a circuit gate by first committing to each wire and then proving the composition. This is easy for linear gates.
This commit-and-prove approach allows VOLEitH to efficiently prove the evaluation of symmetric ciphers, which are quantum-resistant. The transformation to a non-interactive protocol follows the standard MPCitH method: the prover commits to all secret values, a challenge is used to select a subset to reveal, and the prover proves consistency.
Efficient implementations operate over two mathematical fields (binary and prime) simultaneously, allowing these ZK circuits to handle both arithmetic and bitwise functions (like XORs) efficiently. Based on this foundation, a recent talk teased the potential for blind signatures from the multivariate quadratic signature scheme MAYO with sizes of just 7.5 kB and signing/verification times under 50 ms.
The VOLEitH approach, as a general-purpose solution system, represents a promising new direction for performant constructions. There are a numberofcompetingin-the-head schemes in the NIST competition for additional signature schemes, including one based on VOLEitH. The current VOLEitH literature focuses on high-performance digital signatures, and an explicit construction for a full anonymous credential system has not yet been proposed. This means that features standard to ACs, such as multi-show unlinkability or the ability to prove relations between attributes, are not yet part of the design, whereas they are explicitly supported by the lattice construction. However, the preliminary results show great potential for performance, and it will be interesting to see the continued cryptanalysis and feature development from this line of VOLEitH in the area of anonymous credentials, especially since the general-purpose construction allows adding features easily.
Medium: promising research direction, no full solution available so far
Closing the gap
My (that is Lena’s) internship focused on a critical question: what should we look at next to build ACs for the Internet? For us, “the right direction” means developing protocols that can be integrated with real world applications, and developed collaboratively at the IETF. To make these a reality, we need researchers to look beyond blind signatures; we need a complete privacy-preserving protocol that combines blind signatures with efficient zero-knowledge proofs and properties like multi-show credentials that have an internal state. The issuance should also be sublinear in communication size with the number of presentations.
So, with the transition to post-quantum cryptography on the horizon, what are our thoughts on the current IETF proposals? A 2022 NIST presentation on the current state of anonymous credentials states that efficient post-quantum secure solutions are basically non-existent. We argue that the last three years show nice developments in lattices and MPCitH anonymous credentials, but efficient post-quantum protocols still need work. Moving protocols into a post-quantum world isn’t just a matter of swapping out old algorithms for new ones. A common approach on constructing post-quantum versions of classical protocols is swapping out the building blocks for their quantum-secure counterpart.
We believe this approach is essential, but not forward-looking. In addition to identifying how modern concerns can be accommodated on old cryptographic designs, we should be building new, post-quantum native protocols.
For ARC, the conceptual path to a post-quantum construction seems relatively straightforward. The underlying cryptography follows a similar structure as the lattice-based anonymous credentials, or, when accepting a protocol with fewer features, the generic post-quantum privacy-pass construction. However, we need to support per-origin rate-limiting, which allows us to transform a token at an origin without leaking us being able to link the redemption to redemptions at other origins, a feature that none of the post-quantum anonymous credential protocols or blind signatures support. Also, ARC is sublinear in communication size with respect to the number of tokens issued, which so far only the hash-and-sign with abort lattices achieve, although the notion of “limited shows” is not present in the current proposal. In addition, it would be great to gauge efficient implementations, especially for blind signatures, as well as looking into efficient zero-knowledge proofs.
For ACT, we need the protocols for ARC and an additional state. Even for the simplest counter, we need the ability to homomorphically subtract from that balance within the credential itself. This is a much more complex cryptographic requirement. It would also be interesting to see a post-quantum double-spend prevention that enforces the sequential nature of ACT.
Working on ACs and other privacy-preserving cryptography inevitably leads to a major bottleneck: efficient zero-knowledge proofs, or to be more exact, efficiently proving hash function evaluations. In a ZK circuit, multiplications are expensive. Each wire in the circuit that performs a multiplication requires a cryptographic commitment, which adds communication overhead. In contrast, other operations like XOR can be virtually “free.” This makes a huge difference in performance. For example, SHAKE (the primitive used in ML-DSA) can be orders of magnitude slower than arithmetization-friendly hash functions inside a ZKP. This is why researchers and implementers are already using Poseidon or Poseidon2 to make their protocols faster.
Currently, Ethereum is seriously considering migrating Ethereum to the Poseidon hash and calls for cryptanalysis, but there is no indication of standardization. This is a problem: papers increasingly use different instantiations of Poseidon to fit their use-case, and there aremoreandmorezero–knowledgefriendlyhashfunctionscomingout, tailored to different use-cases. We would like to see at least one XOF and one hash each for a prime field and for a binary field, ideally with some security levels. And also, is Poseidon the best or just the most well-known ZK friendly cipher? Is it always secure against quantum computers (like we believe AES to be), and are there other attacks like the recentattacks on round-reduced versions?
Looking at algebra and zero-knowledge brings us to a fundamental debate in modern cryptography. Imagine a line representing the spectrum of research: On one end, you have protocols built on very well-analyzed standard assumptions like the SIS problem on lattices or the collision resistance of SHA3. On the other end, you have protocols that gain massive efficiency by using more algebraic structure, which in turn relies on newer, stronger cryptographic assumptions. Breaking novel hash functions is somewhere in the middle.
The answer for the Internet can’t just be to relent and stay at the left end of our graph to be safe. For the ecosystem to move forward, we need to have confidence in both. We need more research to validate the security of ZK-friendly primitives like Poseidon, and we need more scrutiny on the stronger assumptions that enable efficient algebraic methods.
Conclusion
As we’ve explored, the cryptographic properties that make classical ACs efficient, particularly the rich structure of elliptic curves, do not have direct post-quantum equivalents. Our survey of the state of the art from generic compositions using STARKs, to various lattice-based schemes, and promising new directions like MPC-in-the-head, reveals a field full of potential but with no clear winner. The trade-offs between communication cost, computational cost, and protocol rounds remain a significant barrier to practical, large-scale deployment, especially in comparison to elliptic curve constructions.
To bridge this gap, we must move beyond simply building post-quantum blind signatures. We challenge our colleagues in academia and industry to develop complete, post-quantum native protocols that address real-world needs. This includes supporting essential features like the per-origin rate-limiting required for ARC or the complex stateful credentials needed for ACT.
A critical bottleneck for all these approaches is the lack of efficient, standardized, and well-analyzed zero-knowledge-friendly hash functions. We need to research zero-knowledge friendly primitives and build industry-wide confidence to enable efficient post-quantum privacy.
If you’re working on these problems, or you have experience in the management and deployment of classical credentials, now is the time to engage. The world is rapidly adopting credentials for everything from digital identity to bot management, and it is our collective responsibility to ensure these systems are private and secure for a post-quantum future. We can tell for certain that there are more discussions to be had, and if you’re interested in helping to build this more secure and private digital world, we’re hiring 1,111 interns over the course of next year, and have open positions!
The era of agentic commerce is coming, and it brings with it significant new challenges for security. That’s why Cloudflare is partnering with Visa and Mastercard to help secure automated commerce as AI agents search, compare, and purchase on behalf of consumers.
Through our collaboration, Visa developed the Trusted Agent Protocol and Mastercard developed Agent Pay to help merchants distinguish legitimate, approved agents from malicious bots. Both Trusted Agent Protocol and Agent Pay leverage Web Bot Auth as the agent authentication layer to allow networks like Cloudflare to verify traffic from AI shopping agents that register with a payment network.
The challenges with agentic commerce
Agentic commerce is commerce driven by AI agents. As AI agents execute more transactions, merchants need to protect themselves and maintain trust with their customers. Merchants are beginning to see the promise of agentic commerce but face significant challenges:
How can they distinguish a helpful, approved AI shopping agent from a malicious bot or web crawler?
Is the agent representing a known, repeat customer or someone entirely new?
Are there particular instructions the consumer gave to their agent that the merchant should respect?
We are working with Visa and Mastercard, two of the most trusted consumer brands in payments, to address each of these challenges.
Web Bot Auth is the foundation to securing agentic commerce
In May, we shared a new proposal called Web Bot Auth to cryptographically authenticate agent traffic. Historically, agent traffic has been classified using the user agent and IP address. However, these fields can be spoofed, leading to inaccurate classifications and bot mitigations can be applied inaccurately. Web Bot Auth allows an agent to provide a stable identifier by using HTTP Message Signatures with public key cryptography.
As we spent time collaborating with the teams at Visa and Mastercard, we found that we could leverage Web Bot Auth as the foundation to ensure that each commerce agent request was verifiable, time-based, and non-replayable.
Visa’s Trusted Agent Protocol and Mastercard’s Agent Pay present three key solutions for merchants to manage agentic commerce transactions. First, merchants can identify a registered agent and distinguish whether a particular interaction is intended to browse or to pay. Last, merchants can indicate to agents how a payment is expected, whether that is through a network token, browser-use guest checkout, or a micropayment.
This allows merchants that integrate with these protocols to instantly recognize a trusted agent during two key interactions: the initial browsing phase to determine product details and final costs, and the final payment interaction to complete a purchase. Ultimately, this provides merchants with the tools to verify these signatures, identify trusted interactions, and securely manage how these agents can interact with their site.
How it works: leveraging HTTP message signatures
To make this work, an ecosystem of participants need to be on the same page. It all starts with agentdevelopers, who build the agents to shop on behalf of consumers. These agents then interact with merchants, who need a reliable way to assess the request is made on behalf of consumers. Merchants rely on networks like Cloudflare to verify the agent’s cryptographic signatures and ensure the interaction is legitimate. Finally, there are payment networks like Visa and Mastercard, who can link cardholder identity to agentic commerce transactions, helping ensure that transactions are verifiable and accountable.
When developing their protocols, Visa and Mastercard needed a secure way to authenticate each agent developer and securely transmit information from the agent to the merchant’s website. That’s where we came in and worked with their teams to build upon Web Bot Auth. Web Bot Auth proposals specify how developers of bots and agents can attach their cryptographic signatures in HTTP requests by using HTTP Message Signatures.
Both Visa and Mastercard protocols require agents to register and have their public keys (referenced as the keyid in the Signature-Input header) in a well-known directory, allowing merchants and networks to fetch the keys to validate these HTTP message signatures. To start, Visa and Mastercard will be hosting their own directories for Visa-registered and Mastercard-registered agents, respectively
The newly created agents then communicate their registration, identity, and payment details with the merchant using these HTTP Message Signatures. Both protocols build on Web Bot Auth by introducing a new tag that agents must supply in the Signature-Input header, which indicates whether the agent is browsing or purchasing. Merchants can use the tag to determine whether to interact with the agent. Agents must also include the nonce field, a unique sequence included in the signature, to provide protection against replay attacks.
An agent visiting a merchant’s website to browse a catalog would include an HTTP Message Signature in their request to verify their agent is authorized to browse the merchant’s storefront on behalf of a specific Visa cardholder:
Trusted Agent Protocol and Agent Pay are designed for merchants to benefit from its validation mechanisms without changing their infrastructure. Instead, merchants can set the rules for agent interactions on their site and rely upon Cloudflare as the validator. For these requests, Cloudflare will run the following checks:
Confirm the presence of the Signature-Input and Signature headers.
Pull the keyid from the Signature-Input. If Cloudflare has not previously retrieved and cached the key, fetch it from the public key directory.
Confirm the current time falls between the created and expires timestamps.
Check nonce uniqueness in the cache. By checking if a nonce has been recently used, Cloudflare can reject reused or expired signatures, ensuring the request is not a malicious copy of a prior, legitimate interaction.
Check the validity of the tag, as defined by the protocol. If the agent is browsing, the tag should be agent-browser-auth. If the agent is paying, the tag should be agent-payer-auth.
We recently introduced support for x402 transactions into Cloudflare’s Agent SDK, allowing anyone building an agent to easily transact using the new x402 protocol. We will similarly be working with Visa and Mastercard over the coming months to bring support for their protocols directly to the Agents SDK. This will allow developers to manage their registered agent’s private keys and to easily create the correct HTTP message signatures to authorize their agent to browse and transact on a merchant website.
Conceptually, the requests in a Cloudflare Worker would look something like this:
/**
 * Pseudocode example of a Cloudflare Worker acting as a trusted agent.
 * This version explicitly illustrates the signing logic to show the core flow.
 */


// Helper function to encapsulate the signing protocol logic.
async function createSignatureHeaders(targetUrl, credentials) {
    // Internally, this function would perform the detailed cryptographic steps:
    // 1. Generate timestamps and a unique nonce.
    // 2. Construct the 'Signature-Input' header string with all required parameters.
    // 3. Build the canonical 'Signature Base' string according to the spec.
    // 4. Use the private key to sign the base string.
    // 5. Return the fully formed 'Signature-Input' and 'Signature' headers.

    const signedHeaders = new Headers();

    signedHeaders.set('Signature-Input', 'sig2=(...); keyid="..."; ...');
    signedHeaders.set('Signature', 'sig2=:...');
    return signedHeaders;
}


export default {
    async fetch(request, env) {
        // 1. Load the final API endpoint and private signing credentials.
        const targetUrl = new URL(request.url).searchParams.get('target');
        const credentials = {
            privateKey: env.PAYMENT_NETWORK_PRIVATE_KEY,
            keyId: env.PAYMENT_NETWORK_KEY_ID
        };


        // 2. Generate the required signature headers using the helper.
        const signatureHeaders = await createSignatureHeaders(targetUrl, credentials);


        // 3. Attach the newly created signature headers to the request for authentication.
        const signedRequestHeaders = new Headers(request.headers);
        signedRequestHeaders.set('Host', new URL(targetUrl).hostname);
        signedRequestHeaders.set('Signature-Input', signatureHeaders.get('Signature-Input'));
        signedRequestHeaders.set('Signature', signatureHeaders.get('Signature'));


       // 4. Forward the fully signed request to the protected API.
        return fetch(targetUrl, { headers: signedRequestHeaders });
    },
};
We’ll also be creating new managed rulesets for our customers that make it easy to allow agents that are using the Trusted Agent Protocol or Agent Pay. You might want to disallow most automated traffic to your storefront but not miss out on revenue opportunities from agents authorized to make a purchase on behalf of a cardholder. A managed rule would make this straightforward to implement. As the website owner, you could enable a managed rule that automatically allows all trusted agents registered with Visa or Mastercard to come to your site, passing your other bot protection & WAF rules.
These will continue to evolve, and we will incorporate feedback to ensure that agent registration and validation works seamlessly across all networks and aligns with the Web Bot Auth proposal. American Express will also be leveraging Web Bot Auth as the foundation to their agentic commerce offering.
Cloudflare has a unique vantage point: we see not only how changes in technology shape the Internet, but also how new technologies can unintentionally impact different stakeholders. Take, for instance, the increasing reliance by everyday Internet users on AI–powered chatbots and search summaries. On the one hand, end users are getting information faster than ever before. On the other hand, web publishers, who have historically relied on human eyeballs to their website to support their businesses, are seeing a dramaticdecrease in those eyeballs, which can reduce their ability to create original high-quality content. This cycle will ultimately hurt end users and AI companies (whose success relies on fresh, high-quality content to train models and provide services) alike.
We are indisputably at a point in time when the Internet needs clear “rules of the road” for AI bot behavior (a note on terminology: throughout this blog we refer to AI bots and crawlers interchangeably). We have had ongoing cross-functional conversations, both internally and with stakeholders and partners across the world, and it’s clear to us that the Internet at large needs key groups — publishers and content creators, bot operators, and Internet infrastructure and cybersecurity companies — to reach a consensus on certain principles that AI bots should follow.
Of course, agreeing on what exactly those principles are will take time and require continued discussion and collaboration, and a policy framework can’t perfectly capture every technical concern. Nevertheless, we think it’s important to start a conversation that we hope others will join. After all, a rough draft is better than a blank page.
That is why we are proposing the following responsible AI bot principles as starting points:
Public disclosure: Companies should publicly disclose information about their AI bots;
Self-identification: AI bots should truthfully self-identify, eventually replacing less reliable methods, like user agent and IP address verification, with cryptographic verification;
Declared single purpose: AI bots should have one distinct purpose and declare it;
Respect preferences: AI bots should respect and comply with preferences expressed by website operators where proportionate and technically feasible;
Act with good intent: AI bots must not flood sites with excessive traffic or engage in deceptive behavior.
Each principle is discussed in greater detail below. These principles focus on AI bots because of the impact generative AI is having on the Internet, but we have already seen these practices in action with other types of (non-AI) bots as well. We believe these principles will help move the Internet in a better direction. That said, we acknowledge that they are a starting point for this conversation, which requires input from other stakeholders. The Internet has always been a collaborative place for innovation, and these principles should be seen as equally dynamic and evolving.
While we have recently focused our attention on AI crawlers, Cloudflare has long been a leader in the bot management space, helping our customers protect their websites from unwanted — and even malicious —traffic. We also want to make sure that anyone — whether they’re our customer or not — can see which AI bots are abiding by all, some, or none of these best practices.
But we aren’t ignorant to the fact that companies operating crawlers are also adapting to a new Internet landscape — and we genuinely believe that most players in this space want to do the right thing, while continuing to innovate and propel the Internet in an exciting direction. Our hope is that we can use our expertise and unique vantage point on the Internet to help bring seemingly incompatible parties together and find a path forward — continuing our mission of helping to build a better Internet for everyone.
Responsible AI bot principles
The following principles are a launchpad for a larger conversation, and we recognize that there is work to be done to address many nuanced perspectives. We envision these principles applying to AI bots but understand that technical complexity may require flexibility. Ultimately, our goal is to emphasize transparency, accountability, and respect for content access and use preferences. If these principles fall short of that — or fail to consider other important priorities — we want to know.
Principle #1: Public disclosure
Companies should publicly disclose information about their AI bots. The following information should be publicly available and easy to find:
Identity: information that helps external parties identify a bot, e.g., user agent, relevant IP address(es), and/or individual cryptographic identification (more on this below, in Principle #2: Self-identification).
Operator: the legal entity responsible for the AI bot, including a point of contact (e.g., for reporting abuse);
Purpose: for which purpose the accessed data will be used, i.e., search, AI-input, or training (more on this below, in Principle #3: Declared Single Purpose).
OpenAI is an example of a leading AI company that clearly discloses their bots, complete with detailed explanations of each bot’s purpose. The benefits of this disclosure are apparent in the subsequent principles. It helps website operators validate that a given request is in fact coming from OpenAI and what its purpose is (e.g., search indexing or AI model training). This, in turn, enables website operators to control access to and use of their content through preference expression mechanisms, like robots.txt files.
Principle #2: Self-identification
AI bots should truthfully self-identify. Not only should information about bots be disclosed in a publicly accessible location, this information should also be clearly communicated by bots themselves, e.g., through an HTTP request that conveys the bot’s official user agent and comes from an IP address that the bot claims to send traffic from. Admittedly, this current approach is flawed, as we discuss in more detail below. But until cryptographic verification is more widely adopted, we think relying on user agent and IP verification is better than nothing.
OpenAI’s GPTBot is an example of this principle in action. OpenAI publicly shares the expected full user-agent string for this bot and includes it in its requests. OpenAI also explains this bot’s purpose (“used to make [OpenAI’s] generative AI foundation models more useful and safe” and “to crawl content that may be used in training [their] generative AI foundation models”). And we have observed this bot sending traffic from IP addresses reported by OpenAI. Because site operators see GPTBot’s user agent and IP addresses matching what is publicly disclosed and expected, and they know information about the bot is publicly documented, they can confidently recognize the bot. This enables them to make informed decisions about whether they want to allow traffic from it.
Unfortunately, not all bots uphold this principle, making it difficult for website owners to know exactly which bot operators respect their crawl preferences, much less enforce them. For example, while Anthropic publishes its user agent alone, absent other verifiable information, it’s unclear which requests are truly from Anthropic. And xAI’s bot, grok, does not self-identify at all, making it impossible for website operators to block it. Anthropic and xAI’s lack of identification undermines trust between them and website owners, yet this could be fixed with minimal effort on their parts.
A note on cryptographic verification and the future of Principle #2
Truthful declaration of user agent and dedicated IP lists have historically been a functional way to verify. But in today’s rapidly-evolving bot climate, bots are increasingly vulnerable to being spoofed by bad actors. These bad actors, in turn, ignore robots.txt, which communicates allow/disallow preferences only on a user agent basis (so, a bad bot could spoof a permitted user agent and circumvent that domain’s preferences).
Ultimately, every AI bot should be cryptographically verified using an accepted standard. This would protect them against spoofing and ensure website operators have the accurate and reliable information they need to properly evaluate access by AI bots. At this time, we believe that Web Bot Auth is sufficient proof of compliance with Principle #2. We recognize that this standard is still in development, and, as a result, this principle may evolve accordingly.
Web Bot Auth uses cryptography to verify bot traffic; cryptographic signatures in HTTP messages are used as verification that a given request came from an automated bot. Our implementation relies on proposed IETF directory and protocol drafts. Initial reception of Web Bot Auth has been very positive, and we expect even more adoption. For example, a little over a month ago, Vercel announced that its bot verification now supports Web Bot Auth. And OpenAI’s ChatGPT agent now signs its requests using Web Bot Auth, in addition to using the HTTP Message Signatures standard.
We envision a future where cryptographic authentication becomes the norm, as we believe this will further strengthen the trustworthiness of bots.
Principle #3: Declared single purpose
AI bots should have one distinct purpose and declare it. Today, some bots self-identify their purpose as Training, Search, or User Action (i.e., accessing a web page in response to a user’s query).
However, these purposes are sometimes combined without clear distinction. For example, content accessed for search purposes might also be used to train the AI model powering the search engine. When a bot’s purpose is unclear, website operators face a difficult decision: block it and risk undermining search engine optimization (SEO), or allow it and risk content being used in unwanted ways.
When operators deploy bots with distinct purposes, website owners are able to make clear decisions over who can access their content. What those purposes should be is up for debate, but we think the following breakdown is a starting point based on bot activity we see. We recognize this is an evolving space and changes may be required as innovation continues:
Search: building a search index and providing search results (e.g., returning hyperlinks and short excerpts from your website’s contents). Search does not include providing AI-generated search summaries;
AI-input: inputting content into one or more AI models, e.g., retrieval-augmented generation (RAG), grounding, or other real-time taking of content for generative AI search answers; and
Training: training or fine-tuning AI models.
Relatedly, bots should not combine purposes in a way that prevents web operators from deliberately and effectively deciding whether to allow crawling.
Let’s consider two AI bots, OAI-SearchBot and Googlebot, from the perspective of Vinny, a website operator trying to make a living on the Internet. OAI-SearchBot has a single purpose: linking to and surfacing websites in ChatGPT’s search features. If Vinny takes OpenAI at face value (which we think it makes sense to do), he can trust that OAI-SearchBot does not crawl his content for training OpenAI’s generative AI models rather, a separate bot (GPTBot, as discussed in Principle #2: Self-identification) does. Vinny can decide how he wants his content used by OpenAI, e.g., permitting its use for search but not for AI training, and feel confident that his choices are respected because OAI-SearchBot only crawls for search purposes, while GPTBot is not granted access to the content in the first place (and therefore cannot use it).
On the other hand, while Googlebot scrapes content for traditional search-indexing (not model training), it also uses that content for inference purposes, such as for AI Overviews and AI Mode. Why is this a problem for Vinny? While he almost certainly wants his content appearing in search results, which drive the human eyeballs that fund his site, Vinny is forced to also accept that his content will appear in Google’s AI-generated summaries. If eyeballs are satisfied by the summary then they never visit Vinny’s website, which leads to “zero-click” searches and undermines Vinny’s ability to financially benefit from his content.
This is a vicious cycle: creating high-quality content, which typically leads to higher search rankings, now inadvertently also reduces the chances an eyeball will visit the site because that same valuable content is surfaced in an AI Overview (if it is even referenced as a source in the summary). To prevent this, Vinny must either opt out of search completely or use snippet controls (which risks degrading how his content appears in search results). This is because the only available signal to opt-out of AI, disallowing Google-Extended, is limited to training and does not apply to AI Overview, which is attached to search. Whether by accident or by design, this setup forces an impossible choice onto website owners.
Finally, the prominent technical argument in favor of combining multiple purposes — that this reduces the crawler operator’s costs — needs to be debunked. To reason by analogy: it’s like arguing that placing one call to order two pizzas is cheaper than placing two calls to order two pizzas. In reality, the cost of the two pizzas (both of which take time and effort to make) remains the same. The extra phone call may be annoying, but its costs are negligible.
Similarly, whether one bot request is made for two purposes (e.g., search indexing and AI model training) or a separate bot request is made for each of two purposes, the costs basically remain the same. For the crawler, the cost of compute is the same because the content still needs to be processed for each purpose. And the cost of two connections (i.e., for two requests) is virtually the same as one. We know this because Cloudflare runs one of the largest networks in the world, handling on average 84 million requests per second, so we understand the cost of requests at Internet scale. (As an aside, while additional crawls incur costs on website operators, they have the ability to choose whether the crawl is worth the cost, especially when bots have a single purpose.)
Principle # 4: Respect preferences
AI bots should respect and comply with preferences expressed by website operators where proportionate and technically feasible. There are multiple options for expressing preferences. Prominent examples include the longstanding and familiar robots.txt, as well as newly emerging HTTP headers.
Given the widespread use of robots.txt files, bots should make a good faith attempt to fetch a robots.txt file first, in accordance with RFC 9309, and abide by both the access and use preferences specified therein. AI bot operators should also stay up to date on how those preferences evolve as a result of a draft vocabulary currently under development by an IETF working group. The goal of the proposed vocabulary is to improve granularity in robots.txt files, so that website operators are empowered to control how their assets are used.
At the same time, new industry standards under discussion may involve the attachment of machine-readable preferences to different formats, such as individual files. AI bot operators should eventually be prepared to comply with these standards, too. One idea currently being explored is a way for site owners to list preferences via HTTP headers, which offer a server-level method of declaring how content should be used.
Principle #5: Act with good intent
AI bots must not flood sites with excessive traffic or engage in deceptive behavior. AI bot behavior should be benign or helpful to website operators and their users. It is also incumbent on companies that operate AI bots to monitor their networks and resources for breaches and patch vulnerabilities. Jeopardizing a website’s security or performance or engaging in harmful tactics is unacceptable.
Nor is it appropriate to appear to comply with the principles, only to secretly circumvent them. Reaffirming a long-standing principle of acceptable bot behavior, AI bots must never engage in stealth crawling or use other stealth tactics to try and dodge detection, such as modifying their user agent, changing their source ASNs to hide their crawling activity, or ignoring robots.txt files. Doing so would undermine the preceding four principles, hurting website operators and worsening the Internet for all.
The road ahead: multi-stakeholder efforts to bring these principles to life
As we continue working on these principles and soliciting feedback, we strive to find a balance: we want the wishes of content creators respected while still encouraging AI innovation. It’s a privilege to sit at the intersection of these important interests and to play a crucial role in developing an agreeable path forward.
We are continuing to engage with right holders, AI companies, policy-makers, and regulators to shape global industry standards and regulatory frameworks accordingly. We believe that the influx of generative AI use need not threaten the Internet’s place as an open source of quality content. Protecting its integrity requires agreement on workable technical standards that reflect the interests of web publishers, content creators, and AI companies alike.
The whole ecosystem must continue to come together and collaborate towards a better Internet that truly works for everyone. Cloudflare advocates for neutral forums where all affected parties can discuss the impact of AI developments on the Internet. One such example is the IETF, which has current work focused on some of the technical aspects being considered. Those efforts attempt to address some, but not all, of the issues in an area that deserves holistic consideration. We believe the principles we have proposed are a step in the right direction — but we hope others will join this complex and important conversation, so that norms and behavior on the Internet can successfully adapt to this exciting new technological age.
How do we embrace the power of AI without losing control?
That was one of our big themes for AI Week 2025, which has now come to a close. We announced products, partnerships, and features to help companies successfully navigate this new era.
Everything we built was based on feedback from customers like you that want to get the most out of AI without sacrificing control and safety. Over the next year, we will double down on our efforts to deliver world-class features that augment and secure AI. Please keep an eye on our Blog, AI Avenue, Product Change Log and CloudflareTV for more announcements.
This week we focused on four core areas to help companies secure and deliver AI experiences safely and securely:
Securing AI environments and workflows
Protecting original content from misuse by AI
Helping developers build world-class, secure, AI experiences
Making Cloudflare better for you with AI
Thank you for following along with our first ever AI week at Cloudflare. This recap blog will summarize each announcement across these four core areas. For more information, check out our “This Week in NET” recap episode also featured at the end of this blog.
Securing AI environments and workflows
These posts and features focused on helping companies control and understand their employee’s usage of AI tools.
Generative AI tools present a trade-off of productivity and data risk. Cloudflare One’s new AI prompt protection feature provides the visibility and control needed to govern these tools, allowing organizations to confidently embrace AI.
Don’t let “Shadow AI” silently leak your data to unsanctioned AI. This new threat requires a new defense. Learn how to gain visibility and control without sacrificing innovation.
Cloudflare will provide confidence scores within our application library for Gen AI applications, allowing customers to assess their risk for employees using shadow IT.
Cloudflare CASB now scans ChatGPT, Claude, and Gemini for misconfigurations, sensitive data exposure, and compliance issues, helping organizations adopt AI with confidence.
Cloudflare MCP Server Portals are now available in Open Beta. MCP Server Portals are a new capability that enable you to centralize, secure, and observe every MCP connection in your organization.
This guide provides best practices for Security and IT leaders to securely adopt generative AI using Cloudflare’s SASE architecture as part of a strategy for AI Security Posture Management (AI-SPM).
Protecting original content from misuse by AI
Cloudflare is committed to helping content creators control access to their original work. These announcements focused on analysis of what we’re currently seeing on the Internet with respect to AI bots and crawlers and significant improvements to our existing control features.
We are extending AI-related insights on Cloudflare Radar with new industry-focused data and a breakdown of bot traffic by purpose, such as training or user action.
Cloudflare now lets websites and bot creators use Web Bot Auth to segment agents from verified bots, making it easier for customers to allow or disallow the many types of user and partner directed.
By mid-2025, training drives nearly 80% of AI crawling, while referrals to publishers (especially from Google) are falling and crawl-to-refer ratios show AI consumes far more than it sends back.
Helping developers build world-class, secure, AI experiences
At Cloudflare we are committing to building the best platform to build AI experiences, all with security by default.
Infire is an LLM inference engine that employs a range of techniques to maximize resource utilization, allowing us to serve AI models more efficiently with better performance for Cloudflare workloads.
We’re expanding Workers AI with new partner models from Leonardo.Ai and Deepgram. Start using state-of-the-art image generation models from Leonardo and real-time TTS and STT models from Deepgram.
Cloudflare built an internal platform called Omni. This platform uses lightweight isolation and memory over-commitment to run multiple AI models on a single GPU.
In AI Avenue, we address people’s fears, show them the art of the possible, and highlight the positive human stories where AI is augmenting — not replacing — what people can do. And yes, we even let people touch AI themselves.
Today, we’re excited to announce new capabilities that make it easier than ever to build real-time, voice-enabled AI applications on Cloudflare’s global network.
Making Cloudflare better for you with AI
Cloudflare logs and analytics can often be a needle in the haystack challenge, AI helps surface and alert to issues that need attention or review. Instead of a human having to spend hours sifting and searching for an issue, they can focus on action and remediation while AI does the sifting.
Cloudy now supercharges analytics investigations and Cloudforce One threat intelligence! Get instant insights from threat events and APIs on APTs, DDoS, cybercrime & more – powered by Workers AI!
Troubleshoot network connectivity issues by using Cloudflare AI-Power to quickly self diagnose and resolve WARP client and network issues.
We thank you for following along this week — and please stay tuned for exciting announcements coming during Cloudflare’s 15th birthday week in September!
Check out the full video recap, featuring insights from Kenny Johnson and host João Tomé, in our special This Week in NET episode (ThisWeekinNET.com) covering everything announced during AI Week 2025.
Empowering content creators in the age of AI with smarter crawling controls and direct communication channels
Imagine you run a regional news site. Last month an AI bot scraped 3 years of archives in minutes — with no payment and little to no referral traffic. As a small company, you may struggle to get the AI company’s attention for a licensing deal. Do you block all crawler traffic, or do you let them in and settle for the few referrals they send?
It’s picking between two bad options.
Cloudflare wants to help break that stalemate. On July 1st of this year, we declared Content Independence Day based on a simple premise: creators deserve control of how their content is accessed and used. Today, we’re taking the next step in that journey by releasing AI Crawl Control to general availability — giving content creators and AI crawlers an important new way to communicate.
AI Crawl Control goes GA
Today, we’re rebranding our AI Audit tool as AI Crawl Control and moving it from beta to general availability. This reflects the tool’s evolution from simple monitoring to detailed insights and control over how AI systems can access your content.
The market response has been overwhelming: content creators across industries needed real agency, not just visibility. AI Crawl Control delivers that control.
Using HTTP 402 to help publishers license content to AI crawlers
Many content creators have faced a binary choice: either they block all AI crawlers and miss potential licensing opportunities and referral traffic; or allow them through without any compensation. Many content creators had no practical way to say “we’re open for business, but let’s talk terms first.”
Our customers are telling us:
We want to license our content, but crawlers don’t know how to reach us.
Blanket blocking feels like we’re closing doors on potential revenue and referral traffic.
We need a way to communicate our terms before crawling begins.
To address these needs, we are making it easier than ever to send customizable402 HTTP status codes.
Our private beta launch of Pay Per Crawl put the HTTP 402 (“Payment Required”) response codes to use, working in tandem with Web Bot Auth to enable direct payments between agents and content creators. Today, we’re making customizable 402 response codes available to every paid Cloudflare customer — not just pay per crawl users.
Here’s how it works: in AI Crawl Control, paying Cloudflare customers will be able to select individual bots to block with a configurable message parameter and send 402 payment required responses. Think: “To access this content, email [email protected] or call 1-800-LICENSE” or “Premium content available via API at api.yoursite.com/pricing.”
On an average day, Cloudflare customers are already sending over one billion 402 response codes. This shows a deep desire to move beyond blocking to open communication channels and new monetization models. With the 402 HTTP status code, content creators can tell crawlers exactly how to properly license their content, creating a direct path from crawling to a commercial agreement. We are excited to make this easier than ever in the AI Crawl Control dashboard.
How to customize your 402 status code with AI Crawl Control:
For Paid Plan Users:
When you block individual crawlers from the AI Crawl Control dashboard, you can now choose to send 402 Payment Required status codes and customize your message. For example: To access this content, email [email protected] or call 1-800-LICENSE.
The response will look like this:
The message can be configured from Settings in the AI Crawl Control Dashboard:
Beyond just blocking AI bots
This is just the beginning. We’re planning to add additional parameters that will let crawlers understand the content’s value, freshness, and licensing terms directly in the 402 response. Imagine crawlers receiving structured data about content quality and update frequency, for example, in addition to contact information.
Meanwhile, pay per crawl continues advancing through beta, giving content creators the infrastructure to automatically monetize crawler access with transparent, usage-based pricing.
What excites us most is the market shift we’re seeing. We’re moving to a world where content creators have clear monetization paths to become active participants in the development of rich AI experiences.
The 402 response is a bridge between two industries that want to work together: content creators whose work fuels AI development, and AI companies who need high-quality data. Cloudflare’s AI Crawl Control creates the infrastructure for these partnerships to flourish.
On the surface, the goal of handling bot traffic is clear: keep malicious bots away, while letting through the helpful ones. Some bots are evidently malicious — such as mass price scrapers or those testing stolen credit cards. Others are helpful, like the bots that index your website. Cloudflare has segmented this second category of helpful bot traffic through our verified bots program, vetting and validating bots that are transparent about who they are and what they do.
Today, the rise of agents has transformed how we interact with the Internet, often blurring the distinctions between benign and malicious bot actors. Bots are no longer directed only by the bot owners, but also by individual end users to act on their behalf. These bots directed by end users are often working in ways that website owners want to allow, such as planning a trip, ordering food, or making a purchase.
Our customers have asked us for easier, more granular ways to ensure specific bots, crawlers, and agents can reach their websites, while continuing to block bad actors. That’s why we’re excited to introduce signed agents, an extension of our verified bots program that gives a new bot classification in our security rules and in Radar. Cloudflare has long recognized agents — but we’re now endowing them with their own classification to make it even easier for our customers to set the traffic lanes they want for their website.
But the bot landscape is constantly evolving. Let’s unpack a common type of verified AI bot — an AI crawler such as GPTBot. Even though the bot performs an array of tasks, the bot’s ultimate purpose is a singular, repetitive task on behalf of the operator of that bot: fetch and index information. Its intelligence is applied to performing that singular job on behalf of that bot owner.
Agents, though, are different. Think about an AI agent tasked by a user to “Book the best deal for a round-trip flight to New York City next month.” These agents sometimes use remote browsing products like Cloudflare’s Browser Rendering and similar products from companies like Browserbase and Anchor Browser. And here is the key distinction: this particular type of bot isn’t operating on behalf of a single company, like OpenAI in the prior example, but rather the end users themselves.
Introducing signed agents
In May, we announced Web Bot Auth, a new method of using cryptography to verify bot and agent traffic. HTTP message signatures allow bots to authenticate themselves and allow customer origins to identify them. This is one of the authentication methods we use today for our verified bots program.
What, exactly, is a signed agent? First, they are agents that are generally directed by an end user instead of a single company or entity. Second, the infrastructure or remote browsing platform the agents use is signing their HTTP requests via Web Both Auth, with Cloudflare validating these message signatures. And last, they comply with our signed agent policy.
The signed agents classification improves on our existing frameworks in a couple of ways:
Increased precision and visibility: we’ve updated the Cloudflare bots and agents directory to include signed agents in addition to verified bots. This allows us to verify the cryptographic signatures of a much wider set of automated traffic, and our customers to granularly apply their security preferences more easily. Bot operators can now submit signed agent applications from the Cloudflare dashboard, allowing bot owners to specify to us how they think we should segment their automated traffic.
Easier controls from security rules: similar to how they can take action on verified bots as a group, our Enterprise customers will be able to take action on signed agents as a group when configuring their security rules. This new field will be available in the Cloudflare dashboard under security rules soon.
To apply to have an agent added to Cloudflare’s directory of bots and agents, customers should complete the Bot Submission Form in the Cloudflare dashboard. Here, they can specify whether the submission should be considered for the signed agents list or the verified bots list. All signed agents will be recognized by their cryptographic signatures through Web Bot Auth validation.
The Bot Submission Form, available in the Cloudflare dashboard for bot owners to submit both verified bot and signed agent applications.
We want to be clear: our verified bots program isn’t going anywhere. In fact, well-behaved and transparent applications that make use of signed agents can further qualify to be a verified bot, if their specific service adheres to our policy. For instance,Cloudflare Radar’s URL Scanner, which relies on Browser Rendering as a service to scan URLs, is a verified bot. While Browser Rendering itself does not qualify to be a verified bot, URL Scanner does, since the bot owner (in this case, Cloudflare Radar) directs the traffic sent by the bot and always identifies itself with a unique Web Bot Auth signature — distinct from Browser Rendering’s signature.
From an agent’s perspective…
Since the launch of Web Bot Auth, our own Browser Rendering product has been sending signed Web Bot Auth HTTP headers, and is always given a bot score of 1 for our Bot Management customers. As of today, Browser Rendering will now show up in this new signed agent category.
We’re also excited to announce the first cohort of agents that we’re partnering with and will be classifying as signed agents: ChatGPT agent, Goose from Block, Browserbase, and Anchor Browser. They are perfect examples of this new classification because their remote browsers are used by their end customers, not necessarily the companies themselves. We’re thrilled to partner with these teams to take this critical step for the AI ecosystem:
“When we built Goose as an open source tool, we designed it to run locally with an extensible architecture that lets developers automate complex workflows. As Goose has evolved to interact with external services and third-party sites on users’ behalf, Web Bot Auth enables those sites to trust Goose while preserving what makes it unique. This authentication breakthrough unlocks entirely new possibilities for autonomous agents.” – Douwe Osinga, Staff Software Engineer, Block
“At Browserbase, we provide web browsing capabilities for some of the largest AI applications. We’re excited to partner with Cloudflare to support the adoption of Web Bot Auth, a critical layer of identity for agents. For AI to thrive, agents need reliable, responsible web access.“ – Paul Klein, CEO, Browserbase
“Anchor Browser has partnered with Cloudflare to let developers ship verified browser agents. This way trustworthy bots get reliable access while sites stay protected.” – Idan Raman, CEO, Anchor Browser
Updated visibility on Radar
We want everyone to be in the know about our bot classifications. Cloudflare began publishing verified bots on our Radar page back in 2022, meaning anyone on the Internet — Cloudflare customer or not — can see all of our verified bots on Radar. We dynamically update the list of bots, but show more than just a list: we announced on Content Independence Day that every verified bot would get its own page in our public-facing directory on Radar, which includes the traffic patterns that we see for each bot.
Our directory has been updated to include both signed agents and verified bots — we share exactly how Cloudflare classifies the bots that it recognizes, plus we surface all of the traffic that Cloudflare observes from these many recognized agents and bots. Through this updated directory, we’re not only giving better visibility to our customers, but also striving to set a higher standard for transparency of bot traffic on the Internet.
Cloudflare Radar’s Bots Directory, which lists verified bots and signed agents. This view is filtered to view only agent entries.
Cloudflare Radar’s signed agent page for ChatGPT agent, which includes its traffic patterns for the last 7 days, from August 21, 2025 to August 27, 2025.
What’s now, what’s next
As of today, the Cloudflare bot directory supports both bots and agents in a more clear-cut way, and customers or agent creators can submit agents to be signed and recognized through their account dashboard. In addition, anyone can see our signed agents and their traffic patterns on Radar. Soon, customers will be able to take action on signed agents as a group within their firewall rules, the same way you can take action on our verified bots.
Agents are changing the way that humans interact with the Internet. Websites need to know what tools are interacting with them, and for the builders of those tools to be able to easily scale. Message signatures help achieve both of these goals, but this is only step one. Cloudflare will continue to make it easier for agents and websites to interact (or not!) at scale, in a seamless way.
We are observing stealth crawling behavior from Perplexity, an AI-powered answer engine. Although Perplexity initially crawls from their declared user agent, when they are presented with a network block, they appear to obscure their crawling identity in an attempt to circumvent the website’s preferences. We see continued evidence that Perplexity is repeatedly modifying their user agent and changing their source ASNs to hide their crawling activity, as well as ignoring — or sometimes failing to even fetch — robots.txtfiles.
The Internet as we have known it for the past three decades is rapidly changing, but one thing remains constant: it is built on trust. There are clear preferences that crawlers should be transparent, serve a clear purpose, perform a specific activity, and, most importantly, follow website directives and preferences. Based on Perplexity’s observed behavior, which is incompatible with those preferences, we have de-listed them as a verified bot and added heuristics to our managed rules that block this stealth crawling.
How we tested
We received complaints from customers who had both disallowed Perplexity crawling activity in their robots.txt files and also created WAF rules to specifically block both of Perplexity’s declared crawlers: PerplexityBot and Perplexity-User. These customers told us that Perplexity was still able to access their content even when they saw its bots successfully blocked. We confirmed that Perplexity’s crawlers were in fact being blocked on the specific pages in question, and then performed several targeted tests to confirm what exact behavior we could observe.
We created multiple brand-new domains, similar to testexample.com and secretexample.com. These domains were newly purchased and had not yet been indexed by any search engine nor made publicly accessible in any discoverable way. We implemented a robots.txt file with directives to stop any respectful bots from accessing any part of a website:
We conducted an experiment by querying Perplexity AI with questions about these domains, and discovered Perplexity was still providing detailed information regarding the exact content hosted on each of these restricted domains. This response was unexpected, as we had taken all necessary precautions to prevent this data from being retrievable by their crawlers.
Obfuscating behavior observed
Bypassing Robots.txt and undisclosed IPs/User Agents
Our multiple test domains explicitly prohibited all automated access by specifying in robots.txt and had specific WAF rules that blocked crawling from Perplexity’s public crawlers. We observed that Perplexity uses not only their declared user-agent, but also a generic browser intended to impersonate Google Chrome on macOS when their declared crawler was blocked.
Declared
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)
20-25m daily requests
Stealth
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/124.0.0.0 Safari/537.36
3-6m daily requests
Both their declared and undeclared crawlers were attempting to access the content for scraping contrary to the web crawling norms as outlined in RFC 9309.
This undeclared crawler utilized multiple IPs not listed in Perplexity’s official IP range, and would rotate through these IPs in response to the restrictive robots.txt policy and block from Cloudflare. In addition to rotating IPs, we observed requests coming from different ASNs in attempts to further evade website blocks. This activity was observed across tens of thousands of domains and millions of requests per day. We were able to fingerprint this crawler using a combination of machine learning and network signals.
An example:
Of note: when the stealth crawler was successfully blocked, we observed that Perplexity uses other data sources — including other websites — to try to create an answer. However, these answers were less specific and lacked details from the original content, reflecting the fact that the block had been successful.
How well-meaning bot operators respect website preferences
In contrast to the behavior described above, the Internet has expressed clear preferences on how good crawlers should behave. All well-intentioned crawlers acting in good faith should:
Be transparent. Identify themselves honestly, using a unique user-agent, a declared list of IP ranges or Web Bot Auth integration, and provide contact information if something goes wrong.
Be well-behaved netizens. Don’t flood sites with excessive traffic, scrape sensitive data, or use stealth tactics to try and dodge detection.
Serve a clear purpose. Whether it’s powering a voice assistant, checking product prices, or making a website more accessible, every bot has a reason to be there. The purpose should be clearly and precisely defined and easy for site owners to look up publicly.
Separate bots for separate activities. Perform each activity from a unique bot. This makes it easy for site owners to decide which activities they want to allow. Don’t force site owners to make an all-or-nothing decision.
Follow the rules. That means checking for and respecting website signals like robots.txt, staying within rate limits, and never bypassing security protections.
OpenAI is an example of a leading AI company that follows these best practices. They clearly outline their crawlers and give detailed explanations for each crawler’s purpose. They respect robots.txt and do not try to evade either a robots.txt directive or a network level block. And ChatGPT Agent is signing http requests using the newly proposed open standard Web Bot Auth.
When we ran the same test as outlined above with ChatGPT, we found that ChatGPT-User fetched the robots file and stopped crawling when it was disallowed. We did not observe follow-up crawls from any other user agents or third party bots. When we removed the disallow directive from the robots entry, but presented ChatGPT with a block page, they again stopped crawling, and we saw no additional crawl attempts from other user agents. Both of these demonstrate the appropriate response to website owner preferences.
How can you protect yourself?
All the undeclared crawling activity that we observed from Perplexity’s hidden User Agent was scored by our bot management system as a bot and was unable to pass managed challenges. Any bot management customer who has an existing block rule in place is already protected. Customers who don’t want to block traffic can set up rules to challenge requests, giving real humans an opportunity to proceed. Customers with existing challenge rules are already protected. Lastly, we added signature matches for the stealth crawler into our managed rule that blocks AI crawling activity. This rule is available to all customers, including our free customers.
What’s next?
We announced Content Independence Day almost one month ago, giving content creators and publishers more control over how their content is accessed. Today, over two and a half million websites have chosen to completely disallow AI training through our managed robots.txt feature or our managed rule blocking AI Crawlers. Every Cloudflare customer is now able to selectively decide which declared AI crawlers are able to access their content in accordance with their business objectives.
We expected a change in bot and crawler behavior based on these new features, and we expect that the techniques bot operators use to evade detection will continue to evolve. Once this post is live the behavior we saw will almost certainly change, and the methods we use to stop them will keep evolving as well.
Cloudflare is actively working with technical and policy experts around the world, like the IETF efforts to standardize extensions to robots.txt, to establish clear and measurable principles that well-meaning bot operators should abide by. We think this is an important next step in this quickly evolving space.
Almost 30 years ago, two graduate students at Stanford University — Larry Page and Sergey Brin — began working on a research project they called Backrub. That, of course, was the project that resulted in Google. But also something more: it created the business model for the web.
The deal that Google made with content creators was simple: let us copy your content for search, and we’ll send you traffic. You, as a content creator, could then derive value from that traffic in one of three ways: running ads against it, selling subscriptions for it, or just getting the pleasure of knowing that someone was consuming your stuff.
Google facilitated all of this. Search generated traffic. They acquired DoubleClick and built AdSense to help content creators serve ads. And acquired Urchin to launch Google Analytics to let you measure just who was viewing your content at any given moment in time.
For nearly thirty years, that relationship was what defined the web and allowed it to flourish.
But that relationship is changing. For the first time in its history, the number of searches run on Google is declining. What’s taking its place? AI.
If you’re like me, you’ve been amazed at the new AI systems that have launched over the last two years and find yourself turning to them to answer questions that, in the past, you may have previously looked to Google. While it’s still early, it seems clear that the interface of the future of the web will look more like ChatGPT than a spartan search box and ten blue links.
Google itself has changed. While ten years ago they presented a list of links and said that success was getting you off their site as quickly as possible, today they’ve added an answer box and more recently AI Overviews which answer users’ questions without them having to leave Google.com. With the answer box they reported that 75 percent of queries were answered without users leaving Google. With the more recent launch of AI Overviews it’s even higher.
While Google’s users may like that, it’s hurting content creators. Google still copies creators’ content, but over the last 10 years, because of the changes to the UI of “search” it’s gotten almost 10 times more difficult for a content creator to get the same volume of traffic. That means it’s 10 times more difficult to generate value from ads, subscriptions, or the ego of knowing someone cares about what you created.
And that’s the good news. It’s even worse with today’s AI tools. With OpenAI, it’s 750 times more difficult to get traffic than it was with the Google of old. With Anthropic, it’s 30,000 times more difficult. The reason is simple: increasingly we aren’t consuming originals, we’re consuming derivatives.
The problem is whether you create content to sell ads, sell subscriptions, or just to know that people value what you’ve created, an AI-driven web doesn’t reward content creators the way that the old search-driven web did. And that means the deal that Google made to take content in exchange for sending you traffic just doesn’t make sense anymore.
Instead of being a fair trade, the web is being stripmined by AI crawlers with content creators seeing almost no traffic and therefore almost no value.
That changes today, July 1, what we’re calling Content Independence Day. Cloudflare, along with a majority of the world’s leading publishers and AI companies, is changing the default to block AI crawlers unless they pay creators for their content. That content is the fuel that powers AI engines, and so it’s only fair that content creators are compensated directly for it.
But that’s just the beginning. Next, we’ll work on a marketplace where content creators and AI companies, large and small, can come together. Traffic was always a poor proxy for value. We think we can do better. Let me explain.
Imagine an AI engine like a block of swiss cheese. New, original content that fills one of the holes in the AI engine’s block of cheese is more valuable than repetitive, low-value content that unfortunately dominates much of the web today.
We believe that if we can begin to score and value content not on how much traffic it generates, but on how much it furthers knowledge — measured by how much it fills the current holes in AI engines “swiss cheese” — we not only will help AI engines get better faster, but also potentially facilitate a new golden age of high-value content creation.
We don’t know all the answers yet, but we’re working with some of the leading economists and computer scientists to figure them out.
The web is changing. Its business model will change. And, in the process, we have an opportunity to learn from what was great about the web of the last 30 years and what we can make better for the web of the future.
Cloudflare’s mission is to help build a better Internet. I’m proud of the role we’re playing in doing exactly that as the web evolves. And I’m proud that we’re helping content creators stick up and demand value for the content they worked hard to create.
As a site owner, how do you know which bots to allow on your site, and which you’d like to block? Existing identification methods rely on a combination of IP address range (which may be shared by other services, or change over time) and user-agent header (easily spoofable). These have limitations and deficiencies. In our last blog post, we proposed using HTTP Message Signatures: a way for developers of bots, agents, and crawlers to clearly identify themselves by cryptographically signing requests originating from their service.
Since we published the blog post on Message Signatures and the IETF draft for Web Bot Auth in May 2025, we’ve seen significant interest around implementing and deploying Message Signatures at scale. It’s clear that well-intentioned bot owners want a clear way to identify their bots to site owners, and site owners want a clear way to identify and manage bot traffic. Both parties seem to agree that deploying cryptography for the purposes of authentication is the right solution.
Today, we’re announcing that we’re integrating HTTP Message Signatures directly into our Verified Bots Program. This announcement has two main parts: (1) for bots, crawlers, and agents, we’re simplifying enrollment into the Verified Bots program for those who sign requests using Message Signatures, and (2) we’re encouraging all bot operators moving forward to use Message Signatures over existing verification mechanisms. Because Verified Bots are considered authenticated, they do not face challenges from our Bot Management to identify as bots, given they’re already identified as such.
For site owners, no additional action is required – Cloudflare will automatically validate signatures on our edge, and if that validation is a success, that traffic will be marked as verified so that site owners can use the verified bot fields to create Bot Management and WAF rules based on it.
This isn’t just about simplifying things for bot operators — it’s about giving website owners unparalleled accuracy in identifying trusted bot traffic, cutting down on the overhead for cryptographic verification, and fundamentally transforming how we manage authentication across the Cloudflare network.
Become a Verified Bot with Message Signatures
Cloudflare’s existing Verified Bots program is for bots that are transparent about who they are and what they do, like indexing sites for search or scanning for security vulnerabilities. You can see a list of these verified bots in Cloudflare Radar:
A preview of the Verified Bots page on Cloudflare Radar.
In the past, in order to apply to be a verified bot, we used to ask for IP address ranges or reverse DNS names so that we could verify your identity. This required some manual steps like checking that the IP address range is valid and is associated with the appropriate ASN.
With the integration of Message Signatures, we’re aiming to streamline applications into our Verified Bot program. Bots applying with well-formed Message Signatures will be prioritized, and approved more quickly!
At a high level, signing your requests with web bot auth consists of the following steps:
Generate a valid signing key. See Signing Key section for step-by-step instructions.
Host a JSON web key set containing your public key under /.well-known/http-message-signature-directory of your website.
Sign responses for that URL using a Web Bot Auth library, one signature for each key contained in it, to prove you own it. See the Hosting section for step-by-step instructions.
Register that URL with us, using our Verified Bots form. This can be done directly in your Cloudflare account. See our documentation.
Sign requests using a Web Bot Auth library.
As an example, Cloudflare Radar’s URL Scanner lets you scan any URL and get a publicly shareable report with security, performance, technology, and network information. Here’s an example of what a well-formed signature looks like for requests coming from URL Scanner:
GET /path/to/resource HTTP/1.1
Host: www.example.com
User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/119.0.0.0 Safari/537.36
Signature-Agent: "https://web-bot-auth-directory.radar-cfdata-org.workers.dev"
Signature-Input: sig=("@authority" "signature-agent");\
             	 created=1700000000;\
             	 expires=1700011111;\
             	 keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U";\
             	 tag="web-bot-auth"
Signature:sig=jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQTQdi5N5YYKrD+mCT1HA1nZDsi6nJKuHxUi/5Syp3rLWBA==:
Since we’ve already registered URLScanner as a Verified Bot, Cloudflare will now automatically verify that the signature in the Signature header matches the request — more on that later.
Register your bot
Access the Verified Bots submission form on your account. If that link does not immediately take you there, go to your Cloudflare account → Account Home → the three dots next to your account name → Configurations → Verified Bots.
For the verification method, select “Request Signature”, then enter the URL of your key directory in Validation Instructions. Specifying the User-Agent values is optional if you’re submitting a Request Signature bot.
Once your application has gone through our (now shortened) review process, you don’t need to take any further action.
Message Signature verification for origins
Starting today, Cloudflare is ramping up verification of cryptographic signatures provided by automated crawlers and bots. This is currently available for all Free and Pro plans, and as we continue to test and validate at scale, will be released to all Business and Enterprise plans. This means that as time passes, the number of unauthenticated web crawlers should diminish, ensuring most bot traffic is authenticated before it reaches your website’s servers, helping to prevent spoofing attacks.
At a high level, signature verification works like this:
A bot or agent sends a request to a website behind Cloudflare.
Cloudflare’s Message Signature verification service checks for the Signature, Signature-Input, and Signature-Agent headers.
It checks that the incoming request presents a keyid parameter in your Signature-Input that points to a key we already know.
It looks at the expires parameter in the incoming bot request. If the current time is after expiration, verification fails. This guards against replay attacks, preventing malicious agents from trying to pass as a bot by retrying messages they captured in the past.
It checks that you’ve specified a tag parameter indicating web-bot-auth, to indicate your intent that the message be handled using web bot authentication specifically
It looks at all the components chosen in your Signature-Input header, and constructs a signature base from it.
If all pre-flight checks pass, Cloudflare attempts to verify the signature base against the value in Signature field using an ed25519 verification algorithm and the key supplied in keyid.
Verified Bots and other systems at Cloudflare use a successful verification as proof of your identity, and apply rules corresponding to that identity.
If any of the above steps fail, Cloudflare falls back to existing bot identification and mitigation mechanisms. As the system matures, we would strengthen these requirements, and limit the possibilities of a soft downgrade.
As a site owner, you can segment your Verified Bot traffic by its type and purpose by adding the Verified Bot Categories field cf.verified_bot_category as a filter criterion in WAF Custom rules, Advanced Rate Limiting, and Late Transform rules. For instance, to allow the Bibliothèque nationale de France and the Library of Congress, and institutions dedicated to academic research, you can add a rule that allows bots in the Academic Research category.
Where we’re going next
HTTP Message Signatures is a primitive that is useful beyond Cloudflare – the IETF standardized it as part of RFC 9421.
As discussed in our previous blog post, Cloudflare believes that making Message Signatures a core component of bot authentication on the web should follow the same path. The specifications for the protocol are being built in the open, and they have already evolved following feedback.
Moreover, due to widespread interest, the IETF is considering forming a working group around Web Bot Auth. Should you be a crawler, an origin, or even a CDN, we invite you to provide feedback to ensure the solution gets stronger, and suits your needs.
A better, more trusted Internet
For bot, agent, and crawler operators that act transparently and provide vital services for the Internet, we’re providing a faster and more automated path to being recognized as a Verified Bot, reducing manual processes. We trust that this approach improves bot authentication from what were formerly brittle and unreliable authentication methods, to a secure and reliable alternative. It should reduce the overall volume of friction and hurdles genuinely useful bots face.
For site owners, Message Signatures provides better assurance that the bot traffic is legitimate — automatically recognized and allowed, minimizing disruption to essential services (e.g., search engine indexing, monitoring). In line with our commitments to making TLS/SSL and Post-Quantum certificates available for everyone, we’ll always offer the cryptographic verification of Message Signatures for all sites because we believe in a safer and more efficient Internet by fostering a trusted environment for both human and automated traffic.
If you have a feature request, feedback, or are interested in partnering with us, please reach out.
Web crawlers are not new. The World Wide Web Wanderer debuted in 1993, though the first web search engines to truly use crawlers and indexers were JumpStation and WebCrawler. Crawlers are part of one of the backbones of the Internet’s success: search. Their main purpose has been to index the content of websites across the Internet so that those websites can appear in search engine results and direct users appropriately. In this blog post, we’re analyzing recent trends in web crawling, which now has a crucial and complex new role with the rise of AI.
Not all crawlers are the same. Bots, automated scripts that perform tasks across the Internet, come in many forms: those considered non-threatening or “good” (such as API clients, search indexing bots like Googlebot, or health checkers) and those considered malicious or “bad” (like those used for credential stuffing, spam, or scraping content without permission). In fact, around 30% of global web traffic today, according to Cloudflare Radar data, comes from bots, and even exceeds human Internet traffic in some locations.
A new category, AI crawlers, has emerged in recent years. These bots collect data from across the web to train AI models, improving tools and experiences, but also raising issues around content rights, unauthorized use, and infrastructure overload. We aimed to confirm the growth of both search and AI crawlers, examine specific AI crawlers, and understand broader crawler usage.
This is increasingly relevant with the rapid adoption of AI, growing content rights concerns, and data privacy discussions. Some sites and creators are looking to limit or block AI crawlers using tools like robots.txt or firewall rules. Others, like Dutch indie maker and entrepreneur Pieter Levels, have embraced them: “I’m 100% fine with AI crawlers… very important to rank in LLMs [large language models]”.
It’s important to note that crawlers serve different purposes. For example, the facebookexternalhit bot is not included in this analysis, as it is used by Facebook to fetch page content when generating previews for shared links. However, within this post, we are only focusing on AI and search crawlers that are indexing or scraping website content.
AI-only crawlers perspective
Let’s start with an AI-only crawler perspective that we currently have on Cloudflare Radar, focused only on crawlers advertised as AI-related. To identify them, we’re using here a list derived from an open-source project that helps website owners manage and control access to AI crawlers — especially those used to train large language models (LLMs). It also provides guidance on what to include in robots.txtfiles (more on that below). The data shown below is based on matching those crawler names with user-agent strings in HTTP requests. (Further details, including one exception, about this method can be found at the end of the blog post.)
The AI crawler landscape saw a significant shift between May 2024 and May 2025, with GPTBot (from OpenAI) emerging as the dominant force, surging from 5% to 30% share, and Meta-ExternalAgent (from Meta) making a strong new entry at 19%. This growth came at the expense of former leader Bytespider, which plummeted from 42% to 7%, as well as other AI crawlers like ClaudeBot and Amazonbot, which also saw declines. Our data clearly indicates a reordering of top AI crawlers, highlighting the increasing prominence of OpenAI and Meta in this category.
May 2024
May 2025
Rank
Bot Name
Share (May 2024)
Rank
Bot Name
Share (May 2025)
1
Bytespider
42%
1
GPTBot
30%
2
ClaudeBot
27%
2
ClaudeBot
21%
3
Amazonbot
21%
3
Meta-ExternalAgent
19%
4
GPTBot
5%
4
Amazonbot
11%
5
Applebot
4.1%
5
Bytespider
7.2%
Rank
Bot Name
Share (May 2024)
Rank
Bot Name
Share (May 2025)
1
Bytespider
42%
1
GPTBot
30%
2
ClaudeBot
27%
2
ClaudeBot
21%
3
Amazonbot
21%
3
Meta-ExternalAgent
19%
4
GPTBot
5%
4
Amazonbot
11%
5
Applebot
4.1%
5
Bytespider
7.2%
For additional context, the list below includes further information about the bots with higher crawling shares seen above. This information comes from the same open-source list mentioned above and from publications by companies like OpenAI, which explain how their crawlers are used.
GPTBot – OpenAI’s crawler used to improve and train large language models like ChatGPT.
ClaudeBot – Anthropic’s crawler for training and updating the Claude AI assistant.
Meta-ExternalAgent – Meta’s bot likely used for collecting data to train or fine-tune LLMs.
Amazonbot – Amazon’s crawler that gathers data for its search and AI applications.
Bytespider – ByteDance’s AI data collector, often linked to training models like Ernie or TikTok-related AI.
Applebot – Apple’s web crawler primarily for Siri and Spotlight search, possibly used in AI development.
OAI-SearchBot – OpenAI’s search-focused crawler, likely used for retrieving real-time web info for models.
ChatGPT-User – Represents API-based or browser usage of ChatGPT in connection with user interactions.
PerplexityBot – Crawler from Perplexity.ai, which powers their AI answer engine using real-time web data.
Webmasters can inform crawler operators of whether they want these bots and crawlers to access their content by setting out rules in a file called robots.txt, which tells crawlers what pages they should or shouldn’t access. As we’ve seen recently, crawlers honoring your robots.txt policies is voluntary, but Cloudflare announced tools like AI Audit to help content creators to enforce it.
Now, as we’ve seen, the landscape of web crawling is evolving rapidly, driven by the merging roles of search engines and AI. AI is now deeply integrated into search, seen in Google’s AI Overviews and AI Mode, but also in social media platforms, like Meta AI on Instagram. So, let’s broaden our analysis to include these wider AI-driven crawling activities.
General AI and search crawling growth: +18%
A broader view reveals the growth of crawling traffic from both search and AI crawlers over the first few months of 2025. To remove customer growth bias, we’ll analyze trends using a fixed set of customers from specific weeks (a method we’ve used in our Cloudflare Radar Year in Review): the first week of May 2024, a week in November 2024, and the first week of April 2025.
Using that method, we found that AI and search crawler traffic grew by 18% from May 2024 to May 2025 (comparing full-month periods). The increase was even higher, at 48%, when including new Cloudflare customers added during that time. Peak AI and search crawling traffic occurred in April 2025, with a 32% increase compared to May 2024. This confirms that crawling traffic has clearly risen over the past year, but also that growth is not always constant. Google remains the dominant player, and its share is growing too, as we’ll see in the next section.
As the next chart shows, crawling traffic increased sharply in March and April 2025 and remained high, though slightly lower, in May.
The patterns on the above crawling chart also seem to reflect broader seasonal patterns and general human Internet traffic patterns. In 2024, traffic dropped during the summer in the Northern Hemisphere, with August and September being the least active months. And like overall Internet traffic, it then rose in November, when people are typically more online due to shopping and seasonal habits, as we’ve seen in past analyses.
Googlebot crawling grew 96% in one year
Googlebot, which indexes content for Google Search, was clearly the top crawler throughout the period and showed strong growth, up 96% from May 2024 to May 2025, reflecting increased crawling by Google. Crawling traffic peaked in April 2025, reaching 145% higher than in May 2024. It’s also important to mention that Google made changes to its search and launched AI Overviews in its search engine during this time — first in the US in May 2024, then in more countries later.
Two trends stand out when looking at daily data for Google-related crawlers, as shown in the graph below. First, Googlebot and the more recent GoogleOther (a web crawler from 2023 for “research and development”) account for most of Google’s crawling activity. Second, there were two visible drops in crawling traffic: one on December 14, 2024 (around a Google Search update), and another from May 20 to May 28, 2025. That May 20 drop occurred around the same time as the rollout of AI Mode on Google Search in the US, although the timing may be coincidental.
Breakdown of top 20 AI and search web crawlers
Ranking crawlers by their share of total requests gives a clearer picture of which bots are gaining or losing ground, especially among those focused on search and AI. The table below shows a clear trend: some AI bots have grown rapidly since last year (with growth beginning even earlier), while many traditional search crawlers have remained flat or lost share (as in the case of Bing and its Bingbot crawler). The main exception is Googlebot.
The next table shows the percentage share of each crawler out of all crawling traffic generated by this specific cohort of over 30 AI & search crawlers observed by Cloudflare in May 2024 and May 2025. The table below also includes the change in percentage points and the growth or decline in raw request volume. Crawlers are ranked by their share in May 2025. Key crawler shifts include GPTBot rising sharply (+305%), while Bytespider dropped dramatically (-85%).
Rank
Bot name
Share
May 2024
Share
May 2025
Δ percentage-point change
Raw requests growth (May 2024 to May 2025)
1
Googlebot
30%
50%
+20 pp
96%
2
Bingbot
10%
8.7%
-1.3 pp
2%
3
GPTBot
2.2%
7.7%
+5.5 pp
305%
4
ClaudeBot
11.7%
5.4%
-6.3 pp
-46%
5
GoogleOther
4.4%
4.3%
-0.1 pp
14%
6
Amazonbot
7.6%
4.2%
-3.4 pp
-35%
7
Googlebot-Image
4.5%
3.3%
-1.2 pp
-13%
8
Bytespider
22.8%
2.9%
-19.8 pp
-85%
9
Yandex
2.8%
2.2%
-0.7 pp
-10%
10
ChatGPT-User
0.1%
1.3%
+1.2 pp
2,825%
11
Applebot
1.9%
1.2%
-0.7 pp
-26%
12
Timpibot
0.3%
0.6%
+0.3 pp
133%
13
Baiduspider
0.5%
0.4%
-0.1 pp
7%
14
PerplexityBot
<0.01%
0.2%
+0.2 pp
157,490%
15
DuckDuckBot
0.2%
0.1%
-0.1 pp
-16%
16
SeznamBot
0.1%
0.1%
2%
17
Yeti
0.1%
0.1%
47%
18
coccocbot
0.1%
0.1%
-3%
19
Sogou
0.1%
0.1%
-22%
20
Yahoo! Slurp
0.1%
0.0%
-0.1 pp
-8%
Rank
Bot name
Share May 2024
Share May 2025
Δ percentage-point change
Raw requests growth (May 2024 to May 2025)
1
Googlebot
30%
50%
+20 pp
96%
2
Bingbot
10%
8.7%
-1.3 pp
2%
3
GPTBot
2.2%
7.7%
+5.5 pp
305%
4
ClaudeBot
11.7%
5.4%
-6.3 pp
-46%
5
GoogleOther
4.4%
4.3%
-0.1 pp
14%
6
Amazonbot
7.6%
4.2%
-3.4 pp
-35%
7
Googlebot-Image
4.5%
3.3%
-1.2 pp
-13%
8
Bytespider
22.8%
2.9%
-19.8 pp
-85%
9
Yandex
2.8%
2.2%
-0.7 pp
-10%
10
ChatGPT-User
0.1%
1.3%
+1.2 pp
2,825%
11
Applebot
1.9%
1.2%
-0.7 pp
-26%
12
Timpibot
0.3%
0.6%
+0.3 pp
133%
13
Baiduspider
0.5%
0.4%
-0.1 pp
7%
14
PerplexityBot
<0.01%
0.2%
+0.2 pp
157,490%
15
DuckDuckBot
0.2%
0.1%
-0.1 pp
-16%
16
SeznamBot
0.1%
0.1%
2%
17
Yeti
0.1%
0.1%
47%
18
coccocbot
0.1%
0.1%
-3%
19
Sogou
0.1%
0.1%
-22%
20
Yahoo! Slurp
0.1%
0.0%
-0.1 pp
-8%
Based on this data, two major shifts in web crawling occurred between May 2024 and May 2025:
1. Some AI crawlers rose sharply. GPTBot (from OpenAI) increased its share from 2.2% to 7.7% (+5.5 pp), with a 305% rise in requests. This underscores the data demand for training large language models like ChatGPT. GPTBot jumped from #9 in May 2024 to #3 in May 2025.
Another OpenAI crawler, ChatGPT-User, saw requests surge by 2,825%, reaching a 1.3% share. This reflects a large rise in ChatGPT user activity or API-based interactions that involve accessing web content. PerplexityBot (from Perplexity.ai), despite a small 0.2% share, recorded the highest growth rate: a staggering 157,490% increase in raw requests.
Meanwhile, some AI crawlers saw steep declines. ClaudeBot (Anthropic) fell from 11.7% to 5.4% of total traffic and dropped 46% in requests. Bytespider plummeted 85% in request volume, falling from #2 to #8 in crawler share (now at just 2.9%).
Both Amazonbot and Applebot, also considered AI crawlers, saw decreases in share and in raw requests (–35% and –26%, respectively).
2. Google’s dominance expanded. Googlebot’s share rose from 30% to 50%, supporting search indexing, but potentially also having AI-related purposes (such as new AI Overviews in Google Search). And GoogleOther (the crawler introduced in 2023) also increased in crawling traffic, 14%. Other Google crawlers not in the top 20, like Googlebot-News, also grew significantly (+71% in requests). There’s a clear trend of growth in these Google-related web crawlers at a time when the company is investing heavily in combining AI with search.
Also in the search category, Bingbot’s share (from Microsoft) declined slightly from 10% to 8.7% (-1.3 pp), though its raw requests still grew modestly by 2%.
These trends show that web crawling is increasingly dominated by bots from Google and OpenAI, reflecting clear shifts over the course of a year. Google also appears to be adapting how it collects data to support both traditional search and AI-driven features.
Also worth noting is FriendlyCrawler, which no longer appears in the top 20 list as of May 2025 (now ranked #35). It was #14 in May 2024 with a 0.2% share, but saw a 100% drop in requests by May 2025. This bot is known to index and analyze website content, although its owner and purpose remain unclear. Typically, crawlers like this are used for improving search results, market research, or analytics.
robots.txt & AI bots: GPTBot leads twice
Recent data from June 6, 2025, from Cloudflare Radar shows that out of 3,816 domains (from the top 10,000) where we were able to find a robots.txt file, 546 (about 14%) had “allow” or “disallow” (fully or partially) directives targeting AI bots in particular.
This leaves many site owners in a gray area because it’s not always clear how effective robots.txt is in managing AI crawlers. Some site owners may not think to use it specifically for AI bots, while others might be unsure whether these bots even respect robots.txt rules, especially newer or less transparent crawlers. In other cases, sites use partial rules to fine-tune access, trying to balance visibility and protection without fully opting in or out.
The “disallow” rules appear far more often than “allow” rules. The most frequently blocked bot was GPTBot, disallowed by 312 domains (250 fully, 62 partially), followed by CCBot and Google-Extended, as shown in the following graph.
Although GPTBot was the most blocked, it was also the most explicitly allowed, with 61 domains granting access (18 fully, 43 partially). Still, very few sites openly and explicitly allow AI bots, and when they do, it’s usually for limited sections. Note that bots not listed in a site’s robots.txt are effectively allowed by default.
As AI crawling increases, more websites are moving from passive signals like robots.txt to active protections like Web Application Firewalls. The ecosystem is shifting, with a growing focus on enforceable controls.
Note: When we analyze crawler traffic, we compare user-agent tokens found in robots.txt files (like those for AI crawlers) with the actual user-agent strings in HTTP requests. It’s important to note that some robots.txt tokens, such as Google-Extended, aren’t user-agent substrings. As described in RFC 9309, one goal of these token may be to signal the purpose of the crawler. For instance, Google uses Google-Extended in robots.txt to see if your content can be used for AI training, but the traffic itself still comes from standard Google user-agents like Googlebot. Because of this, not every robots.txt entry will have a direct match in HTTP request logs.
Conclusion
As AI crawlers reshape the Internet, websites face both new challenges and new opportunities in managing their online presence.
This analysis highlights the growing impact of AI on web crawling, showing a clear shift from traditional search indexing to data collection for training AI models. The detailed statistics, such as Googlebot’s continued growth and the rapid rise of AI-specific crawlers, offer context for understanding how this space is evolving and what it means for the future of web content access.
The trend toward stronger, enforceable blocking methods, something Cloudflare has also been invested, signals a key shift in how websites may control their interactions with AI systems going forward.
Many publishers, content creators and website owners currently feel like they have a binary choice — either leave the front door wide open for AI to consume everything they create, or create their own walled garden. But what if there was another way?
At Cloudflare, we started from a simple principle: we wanted content creators to have control over who accesses their work. If a creator wants to block all AI crawlers from their content, they should be able to do so. If a creator wants to allow some or all AI crawlers full access to their content for free, they should be able to do that, too. Creators should be in the driver’s seat.
After hundreds of conversations with news organizations, publishers, and large-scale social media platforms, we heard a consistent desire for a third path: They’d like to allow AI crawlers to access their content, but they’d like to get compensated. Currently, that requires knowing the right individual and striking a one-off deal, which is an insurmountable challenge if you don’t have scale and leverage.
What if I could charge a crawler?
We believe your choice need not be binary — there should be a third, more nuanced option: You can charge for access. Instead of a blanket block or uncompensated open access, we want to empower content owners to monetize their content at Internet scale.
We’re excited to help dust off a mostly forgotten piece of the web: HTTP response code 402.
Introducing pay per crawl
Pay per crawl, in private beta, is our first experiment in this area.
Pay per crawl integrates with existing web infrastructure, leveraging HTTP status codes and established authentication mechanisms to create a framework for paid content access.
Each time an AI crawler requests content, they either present payment intent via request headers for successful access (HTTP response code 200), or receive a 402 Payment Required response with pricing. Cloudflare acts as the Merchant of Record for pay per crawl and also provides the underlying technical infrastructure.
Publisher controls and pricing
Pay per crawl grants domain owners full control over their monetization strategy. They can define a flat, per-request price across their entire site. Publishers will then have three distinct options for a crawler:
Allow: Grant the crawler free access to content.
Charge: Require payment at the configured, domain-wide price.
Block: Deny access entirely, with no option to pay.
An important mechanism here is that even if a crawler doesn’t have a billing relationship with Cloudflare, and thus couldn’t be charged for access, a publisher can still choose to ‘charge’ them. This is the functional equivalent of a network level block (an HTTP 403 Forbidden response where no content is returned) — but with the added benefit of telling the crawler there could be a relationship in the future.
While publishers currently can define a flat price across their entire site, they retain the flexibility to bypass charges for specific crawlers as needed. This is particularly helpful if you want to allow a certain crawler through for free, or if you want to negotiate and execute a content partnership outside the pay per crawl feature.
To ensure integration with each publisher’s existing security posture, Cloudflare enforces Allow or Charge decisions via a rules engine that operates only after existing WAF policies and bot management or bot blocking features have been applied.
Payment headers and access
As we were building the system, we knew we had to solve an incredibly important technical challenge: ensuring we could charge a specific crawler, but prevent anyone from spoofing that crawler. Thankfully, there’s a way to do this using Web Bot Auth proposals.
Once registration is accepted, crawler requests should always include signature-agent, signature-input, and signature headers to identify your crawler and discover paid resources.
Once a crawler is set up, determination of whether content requires payment can happen via two flows:
Reactive (discovery-first)
Should a crawler request a paid URL, Cloudflare returns an HTTP 402 Payment Required response, accompanied by a crawler-price header. This signals that payment is required for the requested resource.
The crawler can then decide to retry the request, this time including a crawler-exact-price header to indicate agreement to pay the configured price.
GET /example.html
crawler-exact-price: USD XX.XX
Proactive (intent-first)
Alternatively, a crawler can preemptively include a crawler-max-price header in its initial request.
GET /example.html
crawler-max-price: USD XX.XX
If the price configured for a resource is equal to or below this specified limit, the request proceeds, and the content is served with a successful HTTP 200 OK response, confirming the charge:
HTTP 200 OK
crawler-charged: USD XX.XX
server: cloudflare
If the amount in a crawler-max-price request is greater than the content owner’s configured price, only the configured price is charged. However, if the resource’s configured price exceeds the maximum price offered by the crawler, an HTTP402 Payment Required response is returned, indicating the specified cost. Only a single price declaration header, crawler-exact-price or crawler-max-price, may be used per request.
The crawler-exact-price or crawler-max-price headers explicitly declare the crawler’s willingness to pay. If all checks pass, the content is served, and the crawl event is logged. If any aspect of the request is invalid, the edge returns an HTTP 402 Payment Required response.
Financial settlement
Crawler operators and content owners must configure pay per crawl payment details in their Cloudflare account. Billing events are recorded each time a crawler makes an authenticated request with payment intent and receives an HTTP 200-level response with a crawler-charged header. Cloudflare then aggregates all the events, charges the crawler, and distributes the earnings to the publisher.
Content for crawlers today, agents tomorrow
At its core, pay per crawl begins a technical shift in how content is controlled online. By providing creators with a robust, programmatic mechanism for valuing and controlling their digital assets, we empower them to continue creating the rich, diverse content that makes the Internet invaluable.
We expect pay per crawl to evolve significantly. It’s very early: we believe many different types of interactions and marketplaces can and should develop simultaneously. We are excited to support these various efforts and open standards.
For example, a publisher or new organization might want to charge different rates for different paths or content types. How do you introduce dynamic pricing based not only upon demand, but also how many users your AI application has? How do you introduce granular licenses at internet scale, whether for training, inference, search, or something entirely new?
The true potential of pay per crawl may emerge in an agentic world. What if an agentic paywall could operate entirely programmatically? Imagine asking your favorite deep research program to help you synthesize the latest cancer research or a legal brief, or just help you find the best restaurant in Soho — and then giving that agent a budget to spend to acquire the best and most relevant content. By anchoring our first solution on HTTP response code 402, we enable a future where intelligent agents can programmatically negotiate access to digital resources.
Getting started
Pay per crawl is currently in private beta. We’d love to hear from you if you’re either a crawler interested in paying to access content or a content creator interested in charging for access. You can reach out to us at http://www.cloudflare.com/paypercrawl-signup/ or contact your Account Executive if you’re an existing Enterprise customer.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.