Last month, on our second Content Independence Day, we announced a couple of features designed to give website owners more visibility and control over automated traffic: BotBase added a searchable directory of known bots to the Cloudflare dashboard, while Business Insights helped owners understand how crawlers interact with their content. We know that the ecosystem of bots is vast, making it all the more important for site owners to be able to manage bot traffic sustainably.
But this ecosystem goes both ways. While website owners need to decide which automated traffic they allow, bot operators need a clear way to identify themselves, explain what their bots do, and keep that information current. BotBase works best when both sides can participate.
When we launched BotBase, we said we would build tools to bring bot operators into this ecosystem. Until now, their experience largely ended at submission. After pressing submit, an operator had no easy way to check the submission's status, understand why it was rejected, or update an existing entry. Today, we start to change that with the launch of BotBase for Operators, tackling what bot operators need first: transparency.
A new home for bot submissions
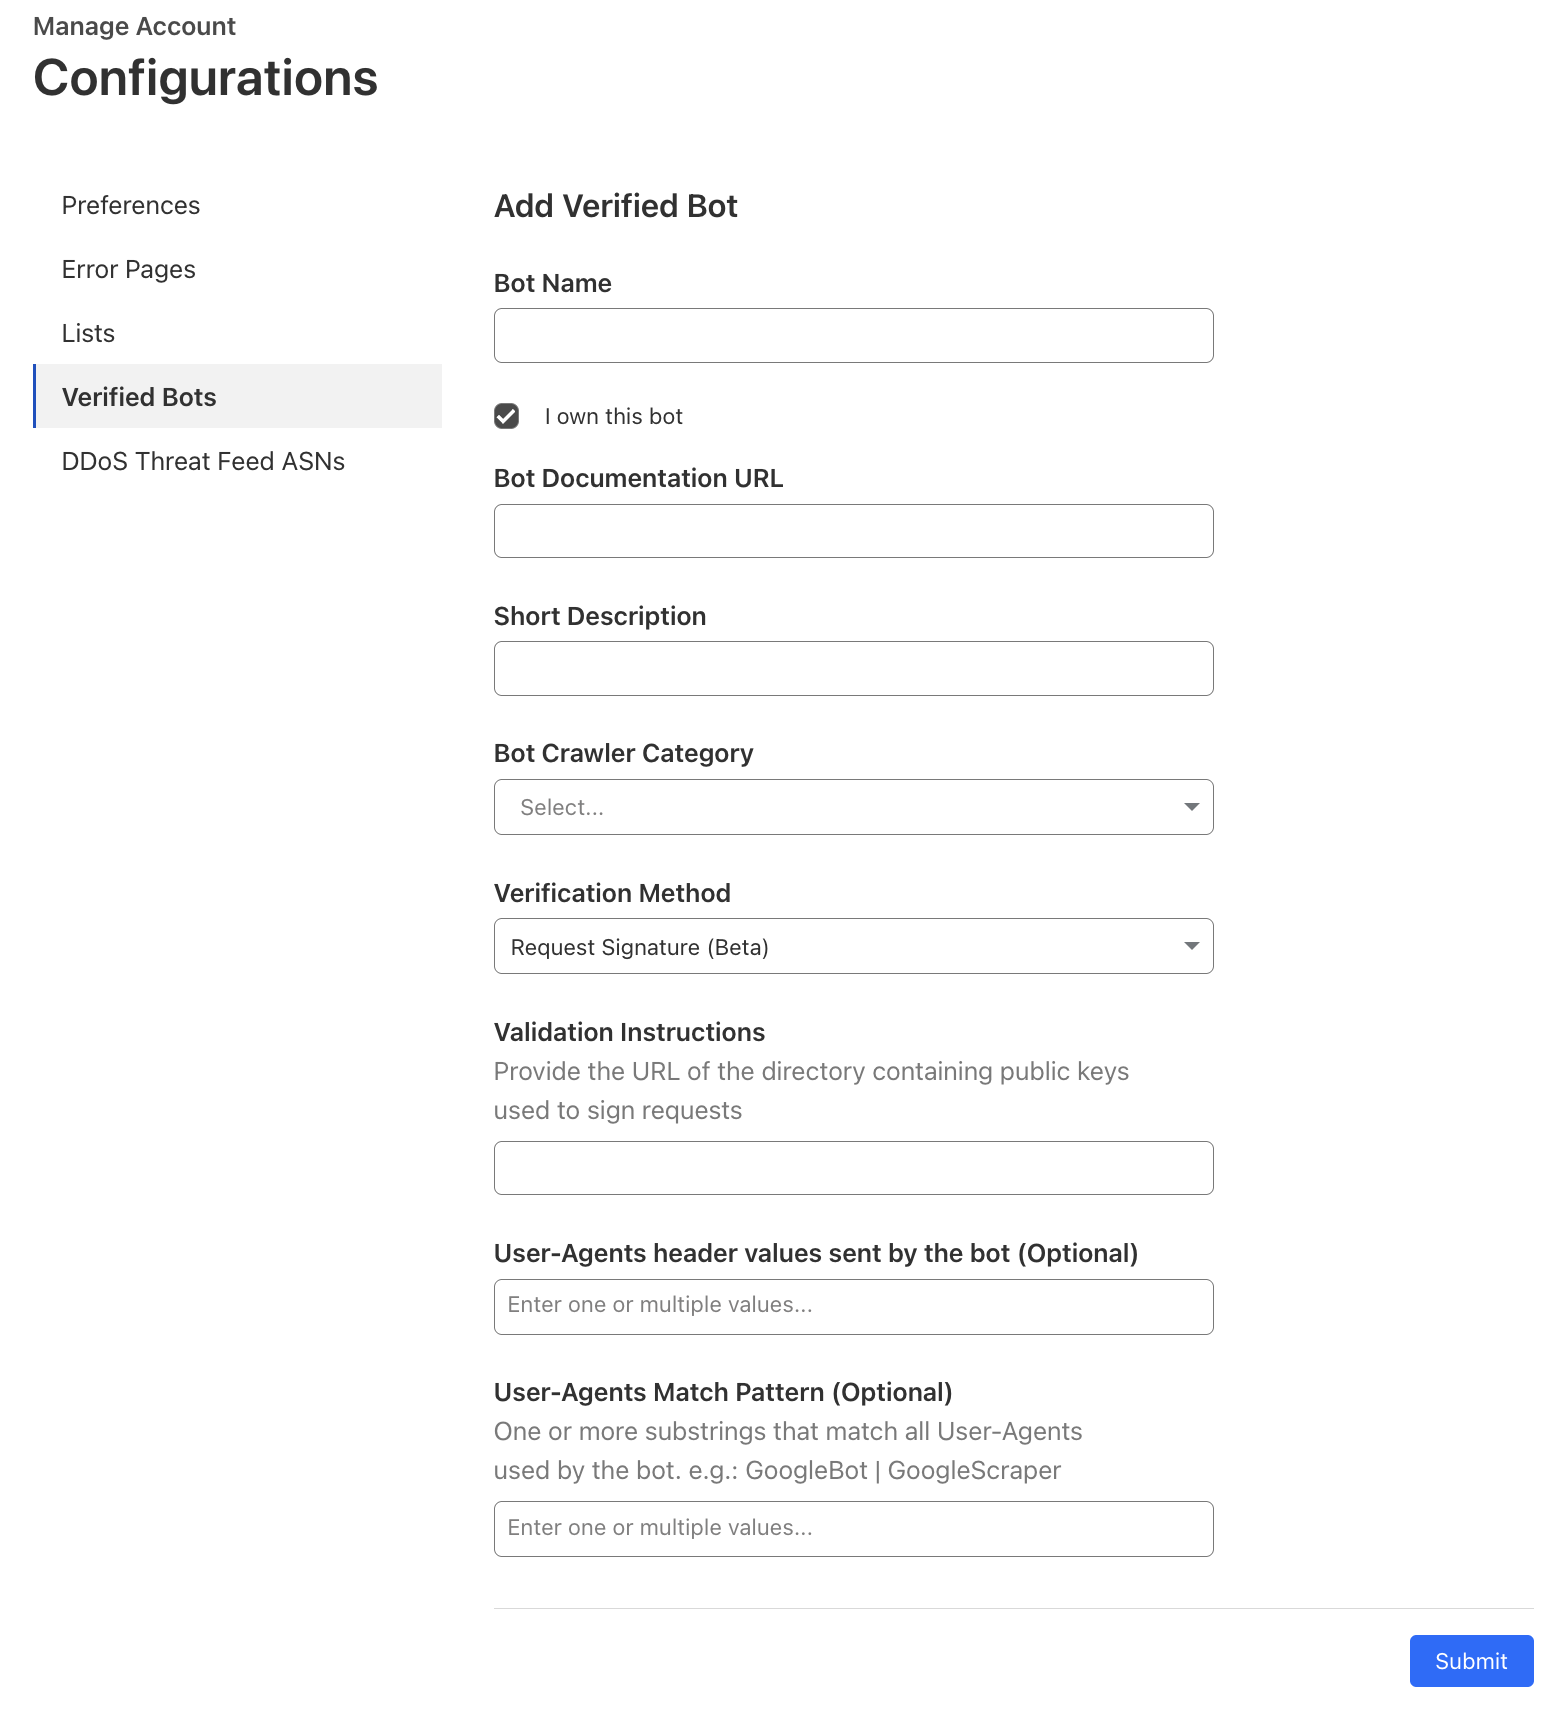
Imagine you’re a bot operator looking to submit your bot to BotBase. Where on the dashboard would you look for such a submission form? Previously, the form lived under Manage Account → Configurations, which tied the bot clearly to your account, but didn’t acknowledge its connection to the bots ecosystem.
Starting today, the bot submission experience has a home next to the rest of your bot and trust tools: Protect & Connect → Application Security → BotBase (new!). All customers can access this today directly from the Cloudflare dashboard.
Here, we’ve split BotBase for Operators by use case:
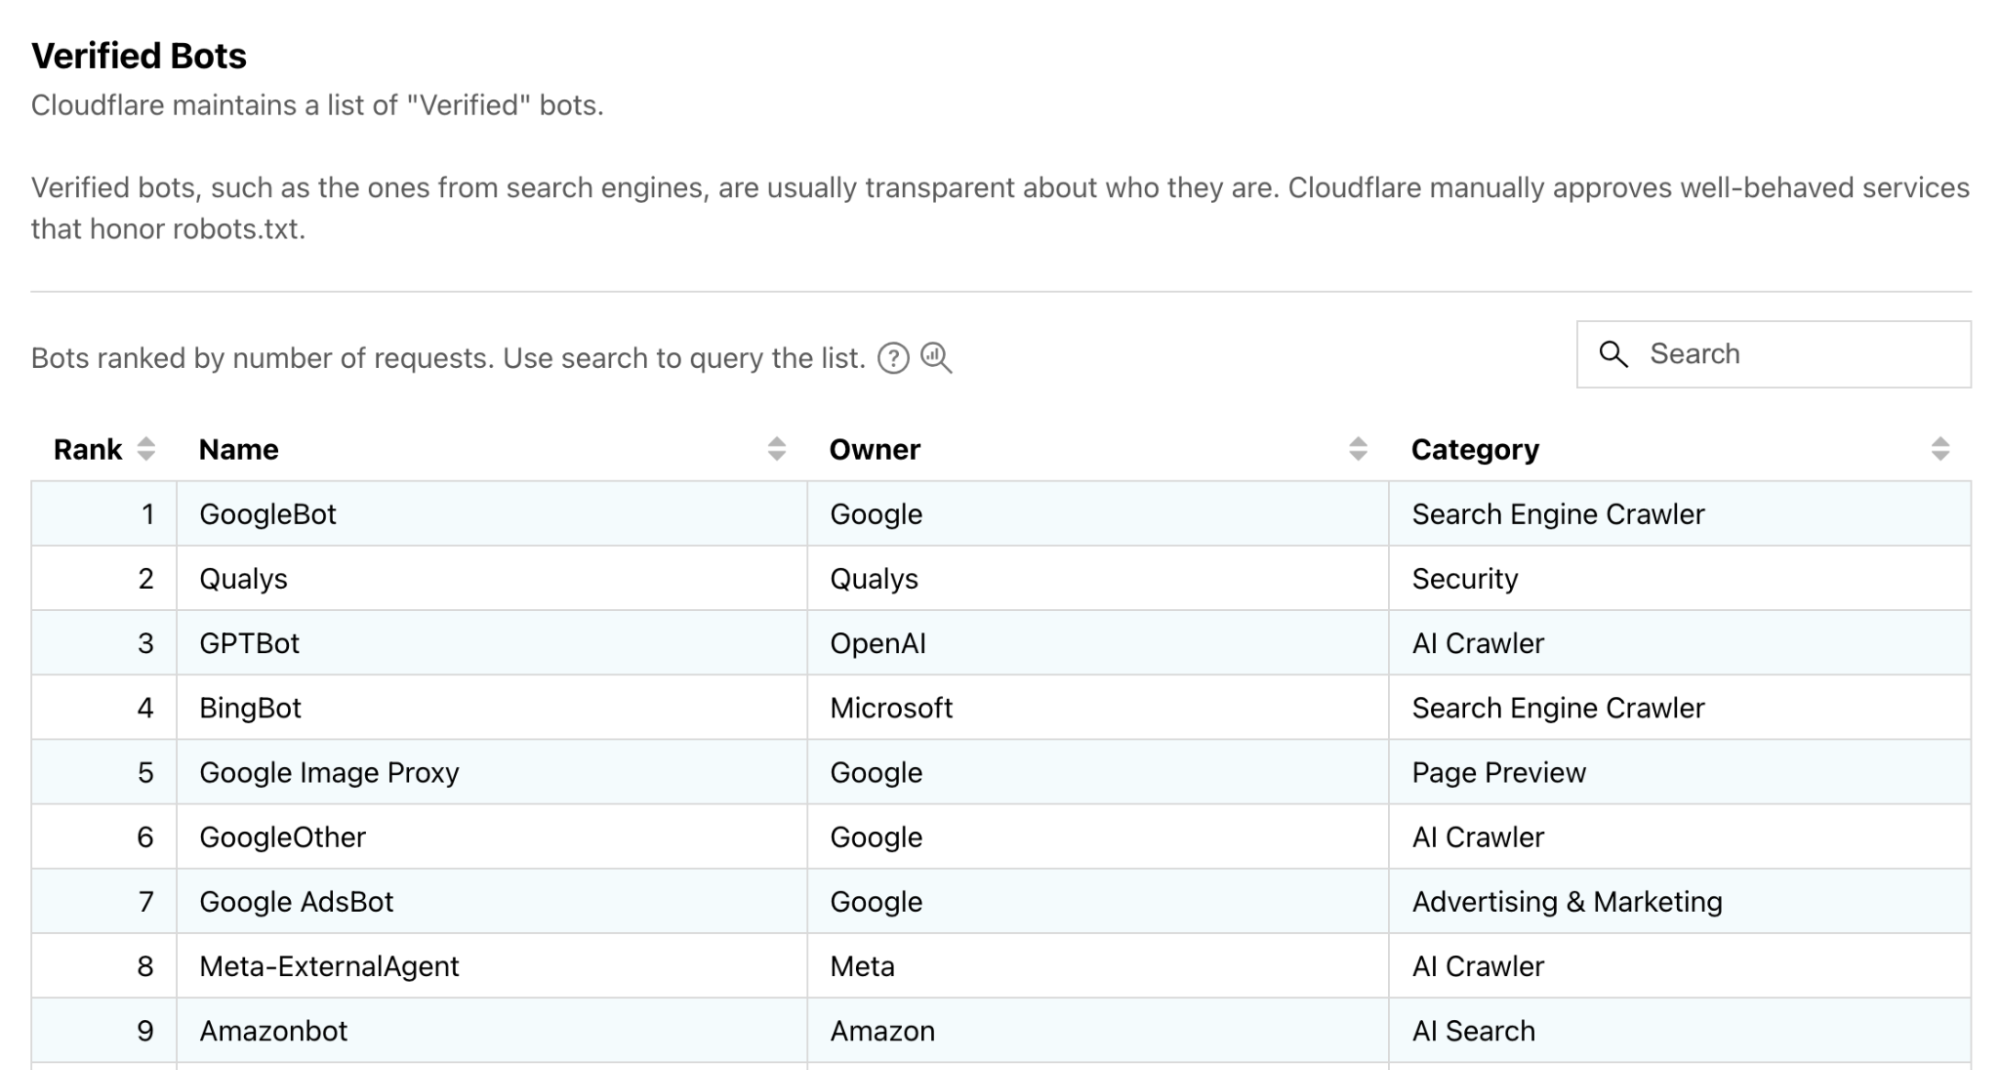
Bots directory — browse, search, and filter the bots Cloudflare already tracks (the same catalogue you can explore on Cloudflare Radar).
Submission form — submit a new bot.
Submission history — track everything you have submitted.
Finding BotBase solves the "where" problem. The "what happens next" problem is the one that we’ve heard is deeply important to bot operators, so we’ll cover that in the rest of this post.
See where your submission stands
We spoke to many bot operators, and the resounding feedback was this: submitting a bot feels like a black box. You fill in the form, press submit, and wait, with no way to tell whether anything happened next.
Now, the Submission history tab shows every bot submitted from your account, each with a clear status:
Waiting for review — we have received your submission and it is in our queue.
Accepted — we have reviewed it and your bot is now tracked in the directory.
Rejected — something in the submission needs to change. We tell you why, with steps you can act on, so you can fix it and resubmit.
Open any submission to see its full details. If it was rejected, you will see the reason why. If it was accepted but we adjusted how your bot is classified, you will see what we changed.
Previously, operators would need to email support just to ask whether their bot got reviewed or to check on their submission's progress. That's exactly the gap we’re closing with this new tab.
Today, the submission form is no longer a black box. Every operator can now view the record of every bot they've submitted starting from today’s launch, with a status you can check anytime. We also provide a way to filter “My bots,” from the Bots directory screen, so you can see all bots that have been submitted under the account with which you’re currently logged in.
Keep your bot's information up to date
A bot's identification details can change over time. You might redesign your website and end up hosting your IP list at a new endpoint. Or you might move from an IP allowlist to signing your traffic with Web Bot Auth, and need your entry to match. Before today, the only way to reflect either change was to fill out the whole form again and submit a brand-new entry. Now, you can edit a submission you have already made.
You can also cancel a submission that is still waiting for review.
We encourage every operator to keep their bot's information current. Accurate details are a key component of how a bot earns and keeps Verified status, which increasingly determines whether sites across Cloudflare's network can easily allow it based on its behavior. Of course, it is ultimately up to the individual site owner to decide what traffic is allowed and what is not.
A submission form built on an updated, pragmatic taxonomy
Picture a bot. Maybe it only crawls pages to build a search index. Maybe it also acts on a user's behalf, or pulls in data for something else entirely. How it uses what it reads matters just as much as what it does.
The new intake form asks you to describe your bot the way it actually behaves. It follows the same behavior and content use model we introduced on July 1, so instead of squeezing your bot into a single label, you now tell us three things.
First, what your bot does. Maybe it only does one thing, like indexing pages for search. Maybe it's an agent acting on a user's behalf, or it collects data, trains models, or supports SEO tools. You can select every behavior that applies, not just the closest match.
Second, how it uses what it reads. A crawler that skims a page for a search snippet is not the same as one that stores that page to train a model. You tell us the level of content use your bot needs, using the same Content Signals model website owners already use to set their own rules. For example, a site's robots.txt might read Content-Signal: search=yes, ai-train=no, use=reference, telling every crawler it's fine to index the page for search and keep a reference, but not to train a model on it. Your bot's content-use declaration is what gets checked against exactly that kind of preference.
Third, who's actually running it. If you operate your bot yourself, straight from your own infrastructure, like a search engine crawling the web to build its own index, that's direct. If you run a platform other companies build on, carrying their traffic without being the one who decided to send it, that's an intermediary. Picture a general-purpose AI assistant fetching a page because someone typed a question into a different company's app built on that assistant's API: the assistant operator runs the infrastructure, but it was someone else's product that decided to send the request. (You can read more about these classifications here.)
That's the full picture: what your bot does, how it treats what it reads, and who's behind it, described as it actually is instead of squeezed into one label. The clearer that picture, the more accurately website owners can decide how to treat your bot.
Faster, more consistent review
Operators also asked for faster reviews. We hear you on this, too.
The number of new bots submitted each year has grown sharply — increasing about 7 times in volume since 2023 — and reviewing every one of them by hand doesn't scale at that pace. Until now, every submission followed the same fully manual path: someone on our team checks it against an internal rubric and makes a judgment call. That kind of review is thorough, but it doesn't scale.
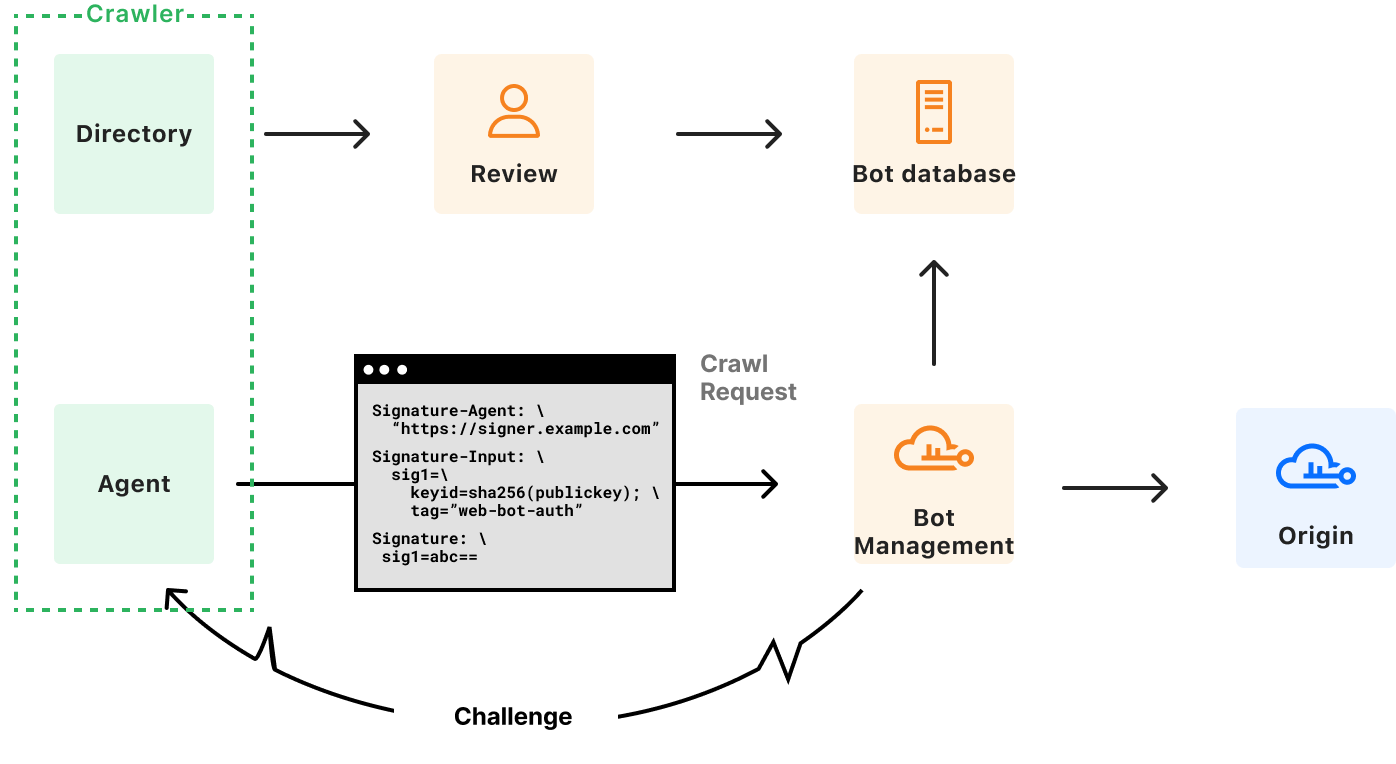
We rebuilt that process to run automatically. Your bot runs through a series of checks — is it a duplicate of one we already track, is your user-agent pattern specific enough to identify your bot without overlapping one that's already registered, and, most importantly, does your claimed verification method actually hold up? We fetch your IP list, confirm your reverse DNS, or validate your Web Bot Auth signature automatically, instead of a person doing it by hand. If everything checks out, your bot can be tracked right away. If something needs a closer look, it's routed to our team with the specific reason already flagged, instead of landing as a blank entry in a queue.
For operators, that means most submissions move faster than before.
Submit your bot today
To join hundreds of bots in BotBase who declare their behavior and content use, and be part of an ecosystem where website owners and bot operators can coexist:
Go to Protect & Connect → Application Security → BotBase in the Cloudflare dashboard.
Open the Submission form and declare your bot: who operates it, what it does, how it uses content, and how it proves its identity.
Submit. Your submission appears in Submission history as Waiting for review.
What's next
This launch is about visibility; there's more coming. Here are our guiding goals:
Visibility, targeted by this launch. This gives operators the ability to see, understand, and edit submissions.
Ownership and observability, being targeted soon. This gives operators the ability to claim bot ownership, manage its live directory entry, and better understand how websites are treating their bot.
Conversation, a longer-term goal. This would open a more sustainable way for bot operators to ask websites to be let in if they can show they provide value rather than harm.
Our vision is to keep expanding BotBase so operators can understand exactly how their bot is treated and get guidance on how to crawl the web more politely, turning a one-way submission into an ongoing relationship.
BotBase started as a directory for website owners. It is becoming a place where bot operators take part in the ecosystem, understand where they stand, and keep their information accurate. If you run a bot, submit it and tell us what you need next. We are building the operator side alongside the operators who use it.
We’re constantly building for the different goals of our customers. Some customers want to optimize for discovery, while others want to protect their content with the strictest security policy. Among these differing policies, there are multiple ways to mitigate bot traffic. Some mechanisms simply state your preference, assuming best intent from crawlers, and other approaches actually lock down content by outright blocking with a Bot Management solution.
We recognize that it's cumbersome to maintain multiple layers of protection on your website. For example, there are cases in which your robots.txt states that a crawler is Disallowed from accessing your website, while your enforcement rules actually don’t block that crawler. When your stated preferences and your enforced rules disagree, some crawlers treat it as a basis to disregard your preferences or try to bypass your enforced rules.
A couple of years ago, Cloudflare announced an easier way to disallow AI training on your website by tackling two of these layers: a managed value of robots.txt that told a fixed list of major Training crawlers not to train on your content, along with edge-enforced blocks to Training crawlers. On July 1, 2026, we launched easier options to manage different kinds of AI traffic use cases. You can say what you want to do about Search, Agent, and Training traffic on your website.
We're announcing Bot Preference Sync, available to all customers from the Free tier to Enterprise. Bot Preference Sync reflects what you've set in your AI bot configuration by updating corresponding preferences to your robots.txt, and it can be turned on or off at any time. No more static file for one use case: we'll help you tailor your robots.txt to reflect what you’ve already configured for different AI bot categories.
New questions facing the Internet
For years, the most pressing question in this space was: "Is my content being used to train AI models without my permission?" It's an important question, and it isn't going away. Alongside this, the questions we increasingly hear are about discoverability and engagement. How do I show up when someone asks an AI assistant something my site can answer? How much of my traffic is coming from AI crawlers versus real people? What content is actually driving referrals, and what is it worth?
The answers differ by business model. Discoverability and engagement are key, top-of-mind issues for any businesses trying to thrive on the modern web, but the funnels for these are different: an e-commerce store may want everything crawled and trained on, so its products surface when a shopper asks a chatbot for "the best sofa for a small apartment." A publisher that monetizes pages with ads may want the opposite: stay in the search index that sends readers to the page, but keep its articles out of model training and, crucially, be able to verify that its content really wasn't used without permission.
There's no single right answer, which is exactly the point. Your controls should reflect your strategy, which is why we've been building tools to give you visibility and choice at every layer. Bot Preference Sync ties these together, so the preference you set is the preference you publish.
The call for Transparency
On July 1, 2026, we made the case that mixed-use crawlers, or “bots that blend search, agent use, and training behind a single user agent,” put site owners at a disadvantage precisely because they make it hard to separate what you want from what you don't. That's still true, and our position on Transparency for site owners hasn't changed.
But there’s more than one way to approach Transparency. We want to reward the operators who are clear about their identity and how they are using the data they crawl. For purposes of bot Verification, the owners of bots that perform both Search and Training will need to provide additional information in order to not be blocked when “Disallow Training” is set. Those requirements are:
The bot must respect, via any mechanism, a “no training” preference in robots.txt
They give site owners a way to opt out of AI summaries.
They provide URL-level visibility into which pages were made available for training, as well metrics on search results, so you can see how your content was used for search and for training.
They can show publicly that Disallowing Training does not hurt your traditional search results.
Bots of leading AI models and service providers that meet these criteria are tracked publicly in the AI bot transparency section in Cloudflare Radar, which includes examples in which best practices are honored, as well as when they are not. Crawlers that don't provide Transparency will not get the benefit of the doubt — they're still blocked when you disallow training. In other words, this is a way of making Transparency the price of admission.
Introducing Bot Preference Sync
Bot Preference Sync is a new feature that keeps your robots.txt reflecting the AI bot preferences you've already set for Search, Agent, and Training on the Cloudflare zone-level dashboard. If a site owner already has a robots.txt file, the contents added by Bot Preference Sync will be prepended to the existing material, so any existing Disallow directives are maintained.
Instead of a site owner maintaining a separate static file, Cloudflare generates or updates your robots.txt based on your configuration, so what you say to the world and what you enforce at the edge are kept in sync.
For Search and Agent, the three options we announced on July 1 remain: Allow, Block on pages that serve ads, or Block everywhere. For Training, we’re refining the option to stop your content being used for training models with the Disallow option:
Disallow: a "no training" preference is written to your robots.txt, so that cooperating mixed-use crawlers who take the extra Transparency step can still access your content for search indexing, since they’re allowing site owners to directly verify how their data is used. Cooperating crawlers honor the preferences in robots.txt, and your Search visibility for cooperating crawlers is unaffected.
Let’s take the example below, in which someone has configured their AI bot policy to say “Allow Search, Allow Agents, Disallow Training.”
Since this example site has Bot Preference Sync on, their robots.txt would prepend something like the following (which has been shortened and anonymized for the sake of the example):
We’ll use bots that we track in BotBase to periodically update the list of bots that is added to robots.txt when you choose to Block or Disallow a given category. The Verified bots that are classified as Search, Agent, and Training can be viewed at any time in our public bots directory.
For all new customers, Bot Preference Sync will be on by default, to make it easier to manage blocks and preferences that reflect the same policy. For existing customers who are using the legacy managed robots.txt feature, we'll prompt you to review and confirm your preferences to transition to the new Bot Preference Sync upon its upcoming launch.
Some customers may want or need to be more hands-on in stating their preferences, for example, if they have a special arrangement with a given company to which they want to grant an exception. Because Bot Preference Sync is designed to tackle policy decisions made category-wide rather than case-by-case, it will not directly read from individual custom rules with more complex logic. Customers with a more fine-tuned security policy always have the option to turn off the sync that sets group policies, and tailor their file to match their custom policy.
We’re also making a change that allows publishers or ad-supported sites to have a different default from other site owners. We’ve created a default to make it easier for publishing sites that rely on ads and expect them to be reserved for human visitors. At the time of onboarding, such customers can select the option, “I monetize from pages with ads on this domain", which will set Training to Disallow as the default. (Customers have the choice to change this setting at any time.) This way, you stay in search while keeping your content out of model training.
For the non-publisher case, new customers will not have any blocks or disallows added by default when they onboard a domain: the choice is up to the customer. You can choose if you want to block Search or Agent or Training at any point, but the starting point will not add any blocks on your behalf.
What's next?
Bot Preference Sync will be available to all customers, on every plan, in the coming week. Keep an eye on our changelog for availability, and watch your dashboard (and inbox) for the prompt to confirm your preferences!
This is one step in a longer effort. We'll keep working with the large bot operators to make sure we're not compromising on familiar challenges (like training without consent) nor emerging questions (like discoverability and engagement). Beneath it all is our effort to promote greater Transparency and control for site owners.
One year ago, we declared Content Independence Day. At the time, we could see what many in the industry were beginning to sense: the fundamental economics of the Internet were shifting. AI adoption was accelerating, publishers were experiencing rapid declines in referral traffic, and AI companies were crawling the web at unprecedented scale, often without clearly declaring intent, and almost always without compensation.
We changed the defaults. For all new domains on Cloudflare, AI training crawlers would be blocked by default unless domain owners chose otherwise. We didn’t do this to wall off the web. We did it because we believed a healthier ecosystem required transparency, control, scarcity, and ultimately, a market where high-quality content could be valued and exchanged fairly.
A year later, that market has emerged. But the transformation of the Internet has happened even faster than we anticipated. In this report, we share key data points that illustrate how quickly the business model of the Internet has shifted – and what this new content market means for publishers and site owners.
Part I: The Internet has changed – faster than anyone expected
The vertical adoption curve
AI is not just another technology cycle. It is a platform shift happening at more than 2x the speed that smartphones were adopted. In just 3.5 years, over 30% of humanity — 2.5 billion active users — has adopted regular use of generative AI. The adoption curve isn’t merely steep: it’s going vertical.
The decline of the open web
Never before have we seen such a rapid change in how humans interact with information, perform work, and spend time online.
The way people use the Internet is changing dramatically. Today, for every hour spent online searching for information, only 15 minutes is spent on the open web. Traditional search behavior is collapsing as users shift to AI-driven discovery and consumption. Instead of visiting multiple sites to source and compare information, users simply type a prompt and receive a nearly instantaneous, consolidated answer.
The agentic Internet is here
This year, agent traffic crossed a historic threshold for the first time: more than 50% of traffic on the Internet is now non-human. This shift has staggering implications for publishers, content owners, and the future of the open web.
Crawlers have changed their purpose
When looking at the crawlers Cloudflare identifies by purpose, the composition of crawler traffic tells the story clearly:
52% of crawler requests are now for AI training as of June 2026, up from 22% in Spring 2025.
Mixed-use crawlers (those blending search, agent use, and training) represent over 36% of activity.
Pure search crawling now represents a small and declining share of overall crawler activity, despite remaining critical for publisher visibility.
As AI training becomes a primary driver of crawler activity, the ability to distinguish between discovery and training becomes increasingly important. Mixed-use crawlers blur that distinction, putting content owners in a difficult position: choose between remaining discoverable in the agentic era, and giving away their most valuable content without compensation.
The old business model is gone
For decades, the economic model of the open web was straightforward. Content creators exchanged access to their content for visibility in search engines, which returned referral traffic. That traffic became the primary mechanism through which publishers, creators, and businesses generated economic value.
But today, that exchange is breaking down. Content is still being crawled, indexed, and used — but increasingly without corresponding traffic being returned to the source. As AI systems answer questions, compare products, conduct research, and complete tasks directly, information across the open web is increasingly becoming part of AI training and retrieval systems. The existential question this raises is simple: if content is consumed without audiences ever visiting the source, how do content creators sustain themselves?
The implications are industry-agnostic
The earliest industries to feel the impact were news organizations and media companies. Today, similar dynamics are impacting businesses across retail, software, IT, and finance. Some of the most heavily crawled categories have seen human traffic decline as much as 40% in less than one year.
Many publishers are now preparing for what they call “Google Zero” — a world where little to no traffic comes from search referrals.
The implications extend to essentially every industry. Any organization that publishes proprietary information on the Internet will need to understand how to operate in an agentic era. This dynamic matters not just to content owners, but to all of us. The Internet is a critical part of the global economy and one of the world’s most important public resources for surfacing information. Ensuring it remains healthy and sustainable is essential for all.
Part II: The market has emerged
What we built
When we launched Content Independence Day, we committed to three things:
Transparency and control for site owners, enabling them to define how their content is accessed and monetized.
Tools that create scarcity, shifting the balance of power back to content owners.
A marketplace where content creators and AI companies of all sizes can discover, license, and determine the value of content more efficiently.
One year later, a market for monetized content is here, and the conditions for a dynamic marketplace are forming.
Transparency and control created scarcity
Historically, publishers have had limited visibility into how AI companies accessed and used their content. As referral traffic declined, that lack of visibility became an economic problem prompting publishers to seek new ways to capture value.
Cloudflare’s attribution, business intelligence, and enforcement tools gave publishers visibility into AI consumption at the network level — an enforcement mechanism far more effective than voluntary standards like robots.txt. For the first time, publishers could determine how their content was accessed and monetized. That control created scarcity, and drove a supply-and-demand content economy.
Scarcity created leverage
Publishers that exercised control over access successfully created scarcity, giving them negotiating leverage that led to better deals. For the first time, publishers gained operator-level attribution data — evidence of how often LLMs attempted to access their content, which competitive LLMs were crawling, what their most in-demand URLs were, and what their crawl-to-referral ratios looked like. This reduced information asymmetry in licensing discussions and enabled publishers to negotiate from a position of knowledge.
Leverage is changing the balance of power
This leverage has empowered our customers. As they have gained greater visibility into how AI systems access and use their content, they’ve become better equipped to understand the implications for their businesses and more confidently articulate the value of the information, brand, and audiences they have built.
As the balance of power between content owners and AI companies begins to change, a licensing economy is emerging:
More than 50 publisher-AI agreements have been signed since 2023.
Major AI companies now actively license content, increasingly recognizing the value of differentiated and premium content.
Collective licensing models continue to emerge and scale.
Large publishers are securing meaningful licensing agreements, demonstrating that content has real economic value within the AI ecosystem.
The conversation is no longer whether content should be compensated. The conversation now is how.
The market is maturing, but inefficiencies remain
Early licensing agreements proved demand exists, but licensing today remains largely bespoke and unlikely to fully replace lost referral, advertising, and affiliate revenue. As a result, publishers are increasingly optimizing for AI consumption alongside traditional human discovery while exploring new monetization pathways.
Supply and demand remain difficult to match efficiently, and while there’s an understanding that not all content carries the same value, content valuation is still unresolved.
The Google convergence problem
No discussion of this market is complete without addressing Google’s unique role. Google remains the dominant gateway to online discovery, accounting for approximately 88% of referral traffic. But increasingly, Google is helping users consume content directly within Google-owned AI experiences.
Discovery and consumption serve fundamentally different purposes. Search drives users to content, while AI-powered experiences increasingly summarize and reuse it without requiring users to visit the source. Website owners view these activities differently because one generates traffic, while the other increasingly substitutes for it.
These differences become especially important when site owners are deciding who should be allowed to access their content and for what purpose. Most leading AI companies separate discovery crawlers from training crawlers, making it relatively simple for publishers to enable content access for one purpose or the other. Google does not. Today, Google has access to about 2x more information than leading AI companies because Google leverages a mixed-use bot that makes it difficult for customers to participate in Google’s search ecosystem without also participating in Google’s AI ecosystem.
Unlike other AI providers, Google’s mixed-use crawler also limits transparency for site owners. Because discovery and AI access are combined into a single crawler, publishers cannot tell why Google is accessing their content or distinguish between traffic used for search and traffic used for AI experiences. They also lose the visibility and evidence that comes from being able to allow or block these activities independently at the network level.
This dynamic has accelerated demand for greater transparency and control, as well as new monetization models to better serve both content owners and AI companies of all sizes.
Part III: A unique view of the ecosystem
Cloudflare sits at the intersection of the emerging agentic economy.
More than 20% of the web sits behind Cloudflare’s network. Of the world’s most-visited websites, 36% rely on our network, and more than 40% of the Fortune 500 are Cloudflare customers. Nearly 80% of leading AI companies use Cloudflare, alongside thousands of developers and emerging AI companies.
This unique position gives us visibility into both sides of the market. We see the content owners creating content, the AI companies consuming it, and the signals increasingly connecting them. That perspective has given us a unique view into how the market has evolved over the past year, and what it now requires.
Part IV: Lessons from an emerging market
As publishers and AI companies adapt to a new agentic economy, Cloudflare has gained a clearer understanding of what the ecosystem now needs.
Transparency must become the standard
Content owners increasingly need visibility and control over who is accessing their content, how it is being used, and for what purpose. AI companies increasingly recognize that transparency builds trust and reduces friction with publishers. Visibility and enforcement are no longer security concerns alone — they have become business requirements that directly influence licensing negotiations and commercial decision making.
To help make transparency the standard, Cloudflare is continuing to invest in enhanced attribution, measurement, and publisher controls that give content owners greater visibility into and control over how their content is accessed and used.
As the industry shifts toward greater transparency, we believe that verifiable bot self-identification and declarations of crawl intent are fundamental to a sustainable ecosystem. Today, more than one-third of crawler activity on our network still comes from mixed-use bots that make it impossible for content owners to distinguish crawl intent. We are actively engaging with the ecosystem and investing in tooling to help drive that number to zero by this time next year.
Better AI requires better signals
Over the past year, it has become increasingly clear that AI companies need more than access to content. They need better ways to determine what to access, when to access it, and how frequently it has changed. Indiscriminate crawling wastes compute for AI companies and creates unnecessary bandwidth burden for publishers, reducing efficiency across the ecosystem.
We believe better answers require better intelligence. We are investing in real-time freshness signals with richer trust, quality, and relevance to help AI companies discover differentiated information while reducing unnecessary crawling across the web.
Markets need better discovery before better pricing
We believe better discovery must precede better pricing. In order for the market to mature, publishers and AI companies need better information about one another. We are investing in richer market intelligence, content signaling, and capabilities that improve discovery between both sides of the ecosystem, laying the foundation for more scalable market mechanisms over time.
Part V. Building the infrastructure for the agentic Internet
One year ago, Content Independence Day introduced a simple idea: content owners should have greater control over how AI companies access and use their information.
Over the past twelve months, that control helped give rise to a market. Transparency created scarcity. Scarcity created leverage. Leverage accelerated licensing. What was once a theoretical discussion about the future of AI and content has become an active market, with publishers, AI companies, and technology providers all adapting to a new set of economic realities.
The market is now entering a new phase that demands new infrastructure. As the Internet becomes increasingly agentic, the underlying systems that support it must evolve to handle permissions, licensing, and commercial transactions at scale. Content owners and AI companies need more efficient ways to connect and exchange value. We believe these capabilities will converge into programmable, scalable mechanisms for content discovery and monetization – reducing friction while unlocking richer forms of value exchange.
Cloudflare’s role is to build the infrastructure and business intelligence, and contribute to the standards that allow the market to determine value more efficiently and help publishers and AI companies participate in a healthier, more dynamic content economy.
The Internet has always evolved. This evolution is faster and more consequential than most. But with the right infrastructure, the right incentives, and a commitment to transparency, we believe the agentic Internet can become more sustainable, more efficient, and better for everyone.
Cloudflare Radar is a hub showcasing global Internet traffic, attack, and technology trends and insights. Powered by data from Cloudflare’s global network, Radar was created to help anyone understand what is happening on the Internet from a security, performance and usage perspective.
Cloudflare’s unique understanding of the Internet comes from its global network — one of the world’s largest, spanning 330+ cities in 100+ countries — and aggregated and anonymized data from Cloudflare’s 1.1.1.1 public DNS Resolver, widely used as a fast and private way to browse the Internet. More than 20% of the web sits behind Cloudflare’s network.
Today, we are announcing the Cloudflare Monetization Gateway, an engine that will give Cloudflare customers the ability to charge for any asset protected by Cloudflare: web pages, datasets, APIs, or MCP tools.
It will provide a single control plane to manage payment policies and access controls across your applications, while also protecting your origin from high payment volumes by handling payment verification and enforcement at the edge. At launch, payments will settle in stablecoins over x402, the open protocol we are building with a coalition of more than 25 industry leaders via the x402 Foundation.
The evolving business model of the web
For 30 years, the web has run on a simple economic bargain: trading content for human attention. That attention has been monetized through advertising, subscriptions, and e-commerce. This bargain funded the Internet as we know it.
But as agents become the dominant Internet users, the model is breaking. An agent does not look at ads or need to maintain a monthly subscription to all the tools it wants to access. It reads a page or consumes a data feed once, takes what it needs, and moves on. Across the web, AI crawlers already request content anywhere from a hundred to tens of thousands of times for every visitor they send back.
This reality demands a new model: usage-based pricing for everything. If attention and e-commerce are moving from websites to AI harnesses and AI-written software, then agents should pay for the inputs they need — training data, inference content, developer tooling, and API usage. The natural unit of payment for software is the request, the token, or the outcome, not the seat or the month. A few examples of what that could look like:
A few cents per web search, billed per call
\$0.001 base fee plus a \$0.01 per MB charge for an upload endpoint
\$0.99 per resolved support escalation, paid only when the work succeeds
This is the same shift behind paying creators when an answer engine uses their content — a fair exchange of value whenever content or a resource is used, priced on neutral rails built for the purpose. People often envision an agent buying high-priced assets like web domains, but most of what an agent pays for sits upstream of any checkout, and is priced far lower.
Some of the Internet already works this way. Cloud and APIs have been sold by the call and by the hour for years, but only to a known buyer: a user signs up, they are issued an API key, and they incur usage-based metered billing. Content mostly skipped payment and ran on advertising instead. These business models have never been able to serve unverified buyers for sub-cent transactions because the payment rails cost too much and took too long to settle. Below a certain price, collecting the payment cost more than the payment was worth.
Historically, usage-based billing was difficult to implement. Businesses needed to effectively become payments companies, running their own accounting to track internal usage in a robust and auditable way. Tracking this usage required significant overhauls of backend systems. Many instead chose per-seat pricing because it is simpler and frequently more profitable.
Agents flip this dynamic. A single agent can do the work of an entire team around the clock, making a flat one-time fee disconnected from actual consumption. At the same time, an agent can make thousands of micropayments without friction, while asking a person to approve each payment would be impossibly burdensome. Usage-based price points are where agents live and where stablecoin-based micropayments shine. That’s because stablecoins (such as Open USD and USDC) allow buyers to transfer tiny sums across the Internet, incurring negligible fees and settling in less than a second. This is not feasible with other payment rails today.
Here’s where we can help. Cloudflare has spent years building usage-based accounting for our own billing systems and for our customers’ analytics. We can dramatically simplify the implementation of usage-based billing for web-based assets thanks to our position as a proxy layer between buyers and sellers. As shown below, with Cloudflare supporting usage-based billing, the evidence of payment can move into the request itself, and the payment validation and the request paths merge.
And here’s the benefit to you: the metering, the payment exchange, and the settlement move off your origin. What stays with you is what matters — your rules, your prices, and your revenue. You will not need to onboard the buyer or stand up a billing system. You will write a rule and agentic buyers will pay for what they use.
A refresher on x402
Last year on Content Independence Day, we gave site owners one-click control over which AI crawlers could reach their content, and with Pay Per Crawl we let them charge crawlers for it. The Monetization Gateway is the next step: instead of only charging crawlers for content, you will be able to charge any caller for any resource, from an API to data to an MCP tool call, and you will not have to build the payment machinery yourself.
x402 is an open protocol that makes it possible to pay over HTTP, named for the 402 status code it finally puts to use. The x402 exchange is simple: a client requests a payment-gated resource. Instead of serving it, the server responds with 402 Payment Required and a small payload that states the price, the accepted asset, and where to pay. The client pays and repeats the request with proof of payment attached. A facilitator verifies, and the server returns the resource. It all happens inside ordinary HTTP requests and responses, with no redirect to a checkout page and no separate payment API to call. Settlement happens peer-to-peer, so any funds that a buyer sends to a seller are directly deposited to the seller’s wallet. We are designing the Monetization Gateway to keep payment overhead low and are aiming for sub-second payment settlement.
Two properties make x402 a good fit for machine payments. The payment amounts can be small, down to fractions of a cent, because the protocol adds almost no overhead. And the buyer needs no account with the seller, because the payment itself is the credential. x402 is rail agnostic, but it is a natural fit for stablecoins, which can settle in under a second for a fraction of a cent with zero chargebacks.
What the Monetization Gateway does
The Monetization Gateway will provide a flexible payment rules API that will allow you to express exactly when you want a caller to pay to access your digital resources.
Here’s how it will work. Tokens, APIs, MCP tool calls, and data already flow through that path. You will decide, as precisely as you want, which of that traffic has to pay. And you will be able to enforce your decisions by writing expressions, similar to expressions that you already write for other Cloudflare rules, in a simple, dedicated product API. The Monetization Gateway will scale with Cloudflare’s global network across 330+ cities, which means that the x402 handshake will occur in close proximity to your buyer. This will reduce request latency and protect your origin.
A few examples of planned capabilities:
Charge for specific REST verbs: Require payment on calls to a specific route, for example $0.01 for every GET or POST request to /api/premium/*.
Variable pricing: Charge variable amounts for tasks of varying complexity, for example, image generation might charge any amount up to $2, depending on the compute used.
Charge only unauthenticated callers: Intercept HTTP 401 “Unauthorized” responses from your origin and return 402 “Payment Required” instead with pricing and payment instructions.
When a request matches, the Monetization Gateway will verify payment before letting it through. You will be able to set these rules in the dashboard, or manage them as code through the Cloudflare API and Terraform, so a paid endpoint is just another part of your infrastructure config.
The Monetization Gateway will initially allow users to require buyers to pay for services and resources in stablecoins. Sellers will be able to use the stablecoins they accumulate for their own transactions or redeem the stablecoins for equivalent fiat currency in their bank account. Using the Monetization Gateway offers a way to increase the addressable market for your products. With the Gateway, agents can request your resource, be told the price, pay, and get the response. No signup, no API key, no prior relationship required. You will decide how much you need to know about that buyer, and you will have the flexibility to require agents to authenticate with Web Bot Auth and apply usage-based pricing against accounts they already hold.
Where we see this going
The Monetization Gateway will turn the request into a payment and give Cloudflare customers new revenue opportunities, but where this goes is far bigger.
An agent is software that acts autonomously on a user’s behalf, and agents are starting to act on their own. Soon they will carry wallets and buy what they need without a person in the loop: a dataset, an API call, a tool, a block of compute. Some of those resources will be free, and some will require proof of who the agent is and who it acts for, through verified agent identity. Many will require both an identity and a payment, and Cloudflare is one of the few places that will be able to settle all of it inside a single request, by verifying the agent, applying the rule, and checking the payment before the origin ever sees the call. The agent becomes the primary buyer on the Internet, and the request becomes the transaction.
There is an enormous amount of value moving across the Internet today that goes unmonetized or undermonetized, not because no one would pay for it, but because the tools to charge for it have never existed. Every useful API call, every answer, every tool invocation an agent makes has value, and almost none of it is paid for today. That is the opportunity in front of us, and it is what the Monetization Gateway will unlock.
This is what we are building toward: an agent-first Internet with Internet-scale settlement built in. Where the people who make something worth paying for get paid by the software that uses it, automatically. And where the smallest new API can reach the same buyers, on the same terms, as the largest company on the web, and the independent creator is paid by the large language models that use their work. That is the next business model of the Internet, and we are building to power it.
Sign up for our waitlist
The Monetization Gateway waitlist is open now for Cloudflare customers. If you’re interested in monetizing your web page, dataset, API, or MCP tool with usage-based pricing, please join our early access list.
Original content is the lifeblood of conversations and curiosities. Imagine a world without it: we could find a thousand ways to regurgitate the same material that’s already been created, but we would witness the decline of fresh ideas and arguments.
Website owners fuel the ecosystem of ideas, news, and interesting tidbits, but they face the increasingly complex challenge of managing traffic to their websites and being paid for their content. While some bot traffic is clearly malicious, it isn’t always obvious when a particular AI crawler is helping or harming your business. To answer this, site owners need granular, reliable data to differentiate between traffic that provides value, and traffic that strains resources while eroding the foundation of their business model: actual humans consuming their content.
At Cloudflare, we hold a core belief: website owners have the right to control access to their content. We want to help website owners maintain their high-quality content and regulate AI traffic.
To provide much-needed clarity and help website owners take control, we’re excited to announce the new Attribution Business Insights dashboard — designed with business decision-makers and publishers in mind.
The new economics of the Internet
For decades, the business model of the Internet relied on a straightforward, unspoken agreement: website owners allowed search engines to crawl their content and, in return, search engines sent readers back to their pages. This symbiotic relationship, where traditional search engines operated with a balanced “crawl-to-referral” ratio, generated the pageviews needed to sustain advertising, affiliate revenue, and subscriptions. Search index crawlers would scan your content a couple of times for each referral sent, so making your website available to crawlers had a clear pipeline to additional revenue. We can think of this as the SEO (Search Engine Optimization) era.
Today, the explosive rise of AI crawlers and agents has broken this contract, plunging the digital publishing industry into an unprecedented crisis. The Internet is risking a transition into a “zero-click” ecosystem where AI chatbots scrape original content to synthesize instant answers — completely bypassing the original sources. We’ve already seen a marked shift from the SEO-only world into an AEO (Answer Engine Optimization) world, and now conversations around GEO (Generative Engine Optimization) are taking center stage.
The imbalance of this new reality is made clear by the crawl-to-referral ratios we see across the Internet today. While traditional search engines had a more balanced ratio of crawls to legitimate visitors referred, major AI crawlers operate on a drastically different, extractive scale. Bots from leading AI companies have been observed with a range of crawl-to-referral ratios: we noted ratios of 118:1 up to nearly 50,000:1 around the time of our Content Independence Day in 2025. In other words, an AI crawler might have crawled your premium content tens of thousands of times just to send back a single visitor. This ratio is fundamentally unfair.
For publishers, this creates a double hit: first, they’re losing out on the crucial referral traffic, ad impressions, and direct audience relationships that fund content creation and journalism. Second, they’re forced to bear the rising infrastructure costs of hosting and serving content to automated bots that offer no commercial value in return. The era in which it makes sense to allow all crawlers in the hopes of being discovered is over.
Introducing Attribution Business Insights
We want website owners to have the facts — the cold, hard numbers to understand which bots are helping their business and which bots are harming it. We also want to make this analysis easier than ever, which is why we’ve designed Attribution Business Insights to cut the noise, focusing on the details that our customers have told us are most important.
Today, the Attribution Business Insights dashboard is available to all Cloudflare Bot Management customers. The new dashboard is designed to deliver a targeted view of bot traffic flowing to your website; unlike traditional analytics tools that may require extensive manual filtering, this dashboard provides you with key insights right away.
We set out to answer the most pressing questions for site owners today: How should you think about AI traffic on your websites? What is the value of different audiences — including humans, non-AI bots, and AI bots? And most importantly, what is your data being used for?
The new Attribution Business Insights dashboard view, which includes insights about bot traffic overall, a site-wide crawl-to-referral ratio, and the distribution of AI bot traffic vs. organic traffic.
To answer these questions, the dashboard displays a powerful array of data and insights:
Bot traffic to content pages: View your overall bot vs. human traffic, as well as the volume of all bots successfully accessing content.
Crawl-to-referral ratios: See your site-wide crawl-to-referral ratio on the scale of 24 hours, seven days, or 30 days. You can also see crawl-to-referral ratios per bot operator (per company that owns one or more bots).
Top bots breakdown: A list of top bots by volume, including their country of origin, bandwidth they take up on your website, and whether you’re currently blocking or allowing them.
You shouldn’t have to be a security expert to understand how AI crawlers affect your business. If website owners want to spend just a few minutes ingesting the high-level insights, they can walk away with a clear temperature check of the effectiveness of their content security policy.
For those who want to do a little more digging to understand how AI companies are making use of their content — or collect information to guide how they want their relationships with AI companies to develop — we show a more granular view organized by bot operator.
Breakdown of bot activity on a website, with important details for each bot such as type, crawl-to-referral ratio, and current action.
By having a consolidated view of companies seeking to access content on your website, you can develop a better baseline of crawler activity. We want this data to equip our customers to step into any business conversation with the facts on their side. Tell Company1 that their crawl volume is twenty times that of Company4’s, and that Company4 is already compensating you for content. Revisit the way that Company2 licenses your content based on their recent activity. This new dashboard propels business conversations to move forward.
How does this new layer of visibility tie into the existing tools you have to protect your website from abuse? In line with other features of Bot Management, the action step still happens in Security rules. To avoid adding noise to the control plane, Attribution Business Insights is intended to be a hub for thoughtful, filtered analytics, rather than another place to take action. This dashboard serves as a central source of information, allowing you to investigate before then taking an action in the same rule engine that governs other abuse mitigations. We also want to be loud and clear about inviting business decision-makers into this dashboard, acknowledging that conversations around AI traffic have a wider set of stakeholders than only security-specialized users.
What’s next
The Attribution Business Insights dashboard is the next critical step in providing website owners with the transparency and control they need to manage evolving AI bot threats, and more broadly, shape the new dynamics of the Internet. We’re already investigating the next iteration with close publishing partners to create a visibility plane that covers security from the perspective of the website owner with valuable, original content to share.
A sneak preview below includes a new view to dissect crawler activity per-article to reveal the appetite that AI companies have for different pieces of content, different campaigns, and so on.
Breakdown of most popular articles, according to traffic volume. Shows key metrics such as AI bot traffic vs. other bot traffic vs. human traffic, both direct and from a referral.
Visibility is the first piece, and there’s more to come to empower website owners to take control of their content in this new age. We encourage all customers of Cloudflare Bot Management — especially those driving business conversations — to access this today for a fresh take on analytics.
For us humans to interact with the online world, we need a gateway: keyboard, screen, browser, device. What is called “human detection” online are patterns that humans use when interacting with such devices. These patterns have changed in recent years: a startup CEO now uses their browser to summarize the news, a tech enthusiast automates the process to book their concert tickets when sales open at night, someone who’s visually impaired enables accessibility on their screen reader, and companies route their employee traffic through zero trust proxies.
At the same time, website owners are still looking to protect their data, manage their resources, control content distribution, and prevent abuse. These problems aren’t solved by knowing whether the client is a human or a bot: There are wanted bots and there are unwanted humans. These problems require knowing intent and behavior. The ability to detect automation remains critical. However, as the distinctions between actors become blurry, the systems we build now should accommodate a future where “bots vs. humans” is not the important data point.
What actually matters is not humanity in the abstract, but questions such as: is this attack traffic, is that crawler load proportional to the traffic it returns, do I expect this user to connect from this new country, are my ads being gamed?
What we discuss with the term “bots” is really two stories. The first is whether website owners should let known crawlers through when they are not getting traffic back. We have touched on this with bot authentication with http message signatures for crawlers that want to identify without being impersonated. The second is the emergence of new clients that do not embed the same behaviors as web browsers historically did, which matters for systems such as private rate limit.
In this post, we explore how web protection works today, and how it must evolve when the line between bot and human is fading.
The Web we had
When we use the Web, we don’t talk directly to the thousands of servers we interact with every day. We use Web browsers. These are also known as “user agents” because they act on our behalf, representing our interests so that we can safely shop, read, and watch the Web without giving sites access to our entire computer or phone.
Websites also have an interest in how browsers work. They want to make sure that their content is presented accurately (fits the screen on mobile, has the right background color, the correct language). Websites also want to ensure that people are able to complete a purchase, read their articles, use their microphone, or sign in securely without a password. They also want people to see the ads beside the articles.
This tension between the interests of browser users and websites has been going on for a long time. Publishers typically want pixel-level control over the experiences of their users, but the people on the other side of the browser often want to use the data they access in ways that weren’t envisioned by the publisher.
Web browser vendors and the standards ecosystem around them have paid careful attention to balancing these interests, sometimes with great controversy. For example, you can use browser extensions to block ads, but over time browsers have restricted what such extensions can do. Accessibility standards (e.g., WCAG) have paved the way for using Web content in ways that aren’t about pixels, backed in many places by regulatory requirements. One can question the specifics of each of those tradeoffs, but they come as a package: if you want to be on the Web, you have to accept it, whether you are a publisher or a user.
Now, however, that balance is shifting. Having an assistant summarize the news or aggregate research is not a new concept, but AI democratizes this capability for everyone. The friction comes from how these emerging clients operate. A human assistant might print an article or take a screenshot without the publisher knowing, but they still use a standard web browser to render the site in the first place. AI agents bypass this step, disrupting the balanced approach to publishers’ vs. users’ rights that browsers built. They quietly fetch the raw data without rendering the page. For publishers, because of their overlap with pre-existing browser traffic, these clients are inherently opaque. Website owners cannot tell if their fetched content is serving one private report (possibly distorted, possibly unattributed) or being ingested to train a model for a million users, which disrupts the predictable (and monetizable) traffic that keeps their sites online.
The implicit agreement that made the Web work is breaking down. To understand how, the next section goes over a common architecture on the Internet.
The client-server model
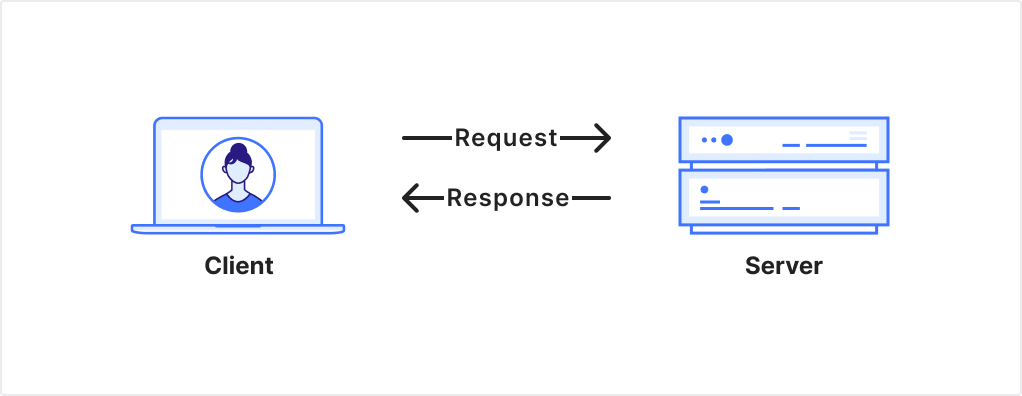
Let’s take a step back, and look at one of the main deployment patterns on the Internet: the client-server model. A client makes a request to a server to obtain a resource:
Figure 1: Client-Server model. A client sends a request which the server responds to.
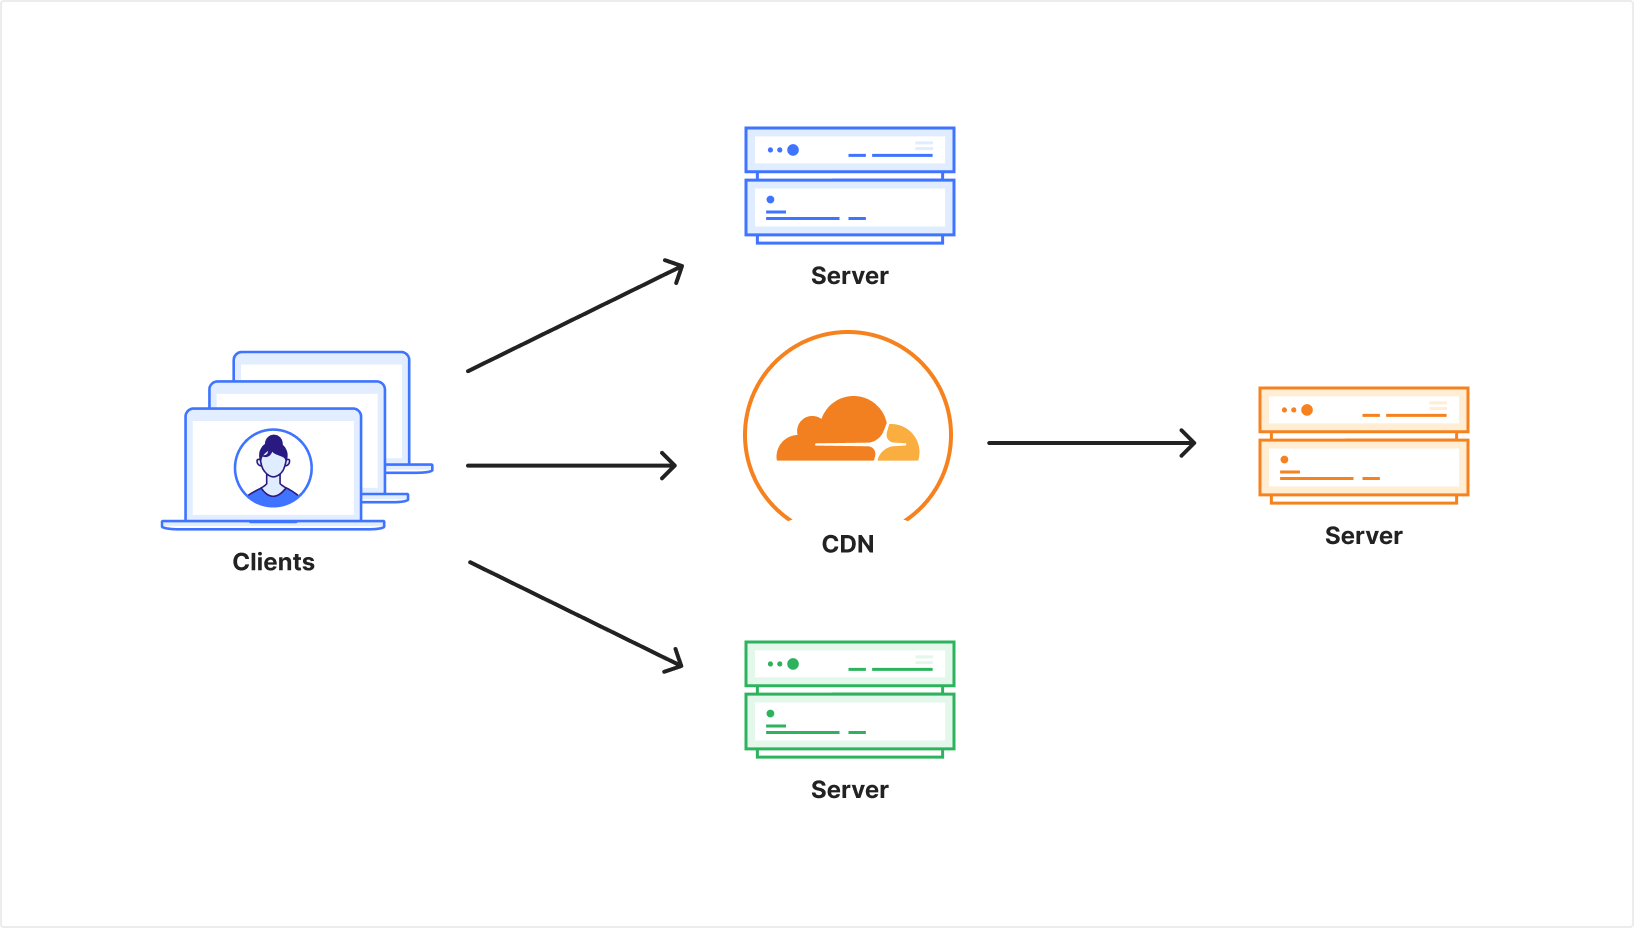
To handle more requests, a website can increase its capacity to serve; it can deploy additional servers or place a cache in front of static traffic. Similarly, the number of requests coming from the client side can increase if one client makes more requests, or if the number of clients multiplies.
Figure 2: Multiple clients send multiple requests to different servers, with one fronted by a CDN.
That simplicity is part of what made the Web successful. It allows many kinds of clients to exist, and it allows the network to evolve without each server needing to know exactly what software is on the other end.
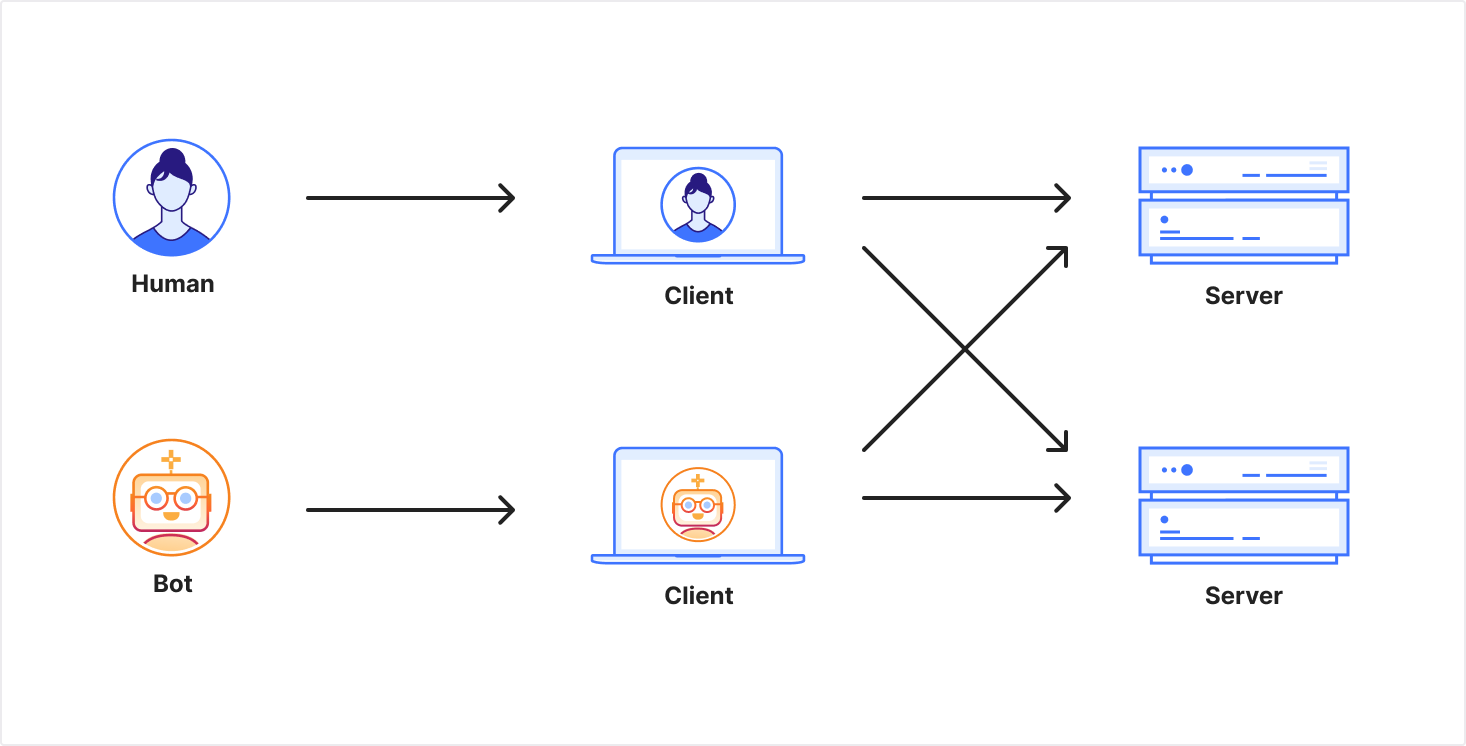
Figure 3: Two different client contexts that send requests to servers. Each server only sees a request, but not the end-user behind it.
That openness also creates uncertainty. A website can see a valid request for a resource, yet it usually cannot know what happens after the response leaves the server: whether the content is rendered for one person using a keyboard, a mouse, and a screen to control a browser; or if it’s an independent program making requests automatically, archiving responses, indexing them, and feeding into a larger system.
Bot management today
This model works surprisingly well. That is why operating a website can be as simple as starting a web server with a connection to the Internet. It holds only until the server has to decide which requests it can afford to serve, trust, or prioritize.
Sometimes that is about capacity. If your service is provisioned to handle 100 requests per second globally, but you’re receiving 200, you have to drop certain requests. If your server only has 1 CPU but incoming requests require 2, you have to drop requests. If the cost of serving 200 is prohibitive, then you have to rate-limit all requests.
You can drop requests at random. It’s possibly unfair, and may miss the target by affecting wanted clients, but it works. In the absence of other signals, there is no other choice.
And capacity is only part of the picture. Servers also try to distinguish among clients for many other reasons: to separate attacks from ordinary traffic, to manage non-malicious load, to prevent extraction of data, to limit ad fraud, to prevent fake account creation, or to stop automated actions being taken on a user’s behalf.
The difficulty is that web clients are unauthenticated by default, while still exposing many partial signals. Therefore, most servers decide to apply access control logic based on the information they receive. If a single IP address is making 10x the number of requests as others, it might be blocked. A server that goes further might infer that this IP address is used by a VPN, and therefore proxies the traffic of more than one user. The service could decide to apply a coefficient: assuming each client can make 10 requests per second, a shared IP address would be allowed 100 rps before seeing their requests being dropped.
That’s one of the keys to bot management: it aims to provide the server with more information about the client to help it make decisions. This information is inherently imprecise, because the client is not under the control of the server. In addition, the same information creates fingerprint vectors that can be used by the server for different purposes such as personalized advertising. This transforms a mitigation vector to a tracking vector.
At a high level, the server sees the following signals from the client:
Passive client signals: required to make a request on the Internet. Clients necessarily send your IP address, and usually establish a TLS session.
Active client signals: voluntarily provided by the client, often invisible to the end user. This includes a User-Agent header or authentication credentials.
Server signals: information the server observes, such as the geographic location of the edge server handling the request, or the local time the request is received.
To limit and cap volumetric abuse, what matters to the origin is the capability and intent of the client to make multiple requests. In the case of an ad-funded website, the origin needs confidence that ads are actually displayed to the end-user. To preserve their brand, origins may want to ensure that the client has specific rendering capabilities: PDF reader, SVG renderer, virtual keyboard. And if the request is coming from an intercepting proxy, the origin may want to ensure that the request actually originates from an end client
If traffic grows then so do the costs to operate. If clients do not generate value, monetary or not, then the server has no incentive to cover those costs.
Different operators respond to this environment differently. Some large crawlers and platforms identify themselves because predictable access is worth the cost of being attributable. It may even help. Others try to avoid identification: because they expect to be blocked, because they seek anonymity, or because they are operating on behalf of end users. The result is an unstable balance built on partial signals.
This is why the human versus bots frame is misleading. What the origin cares about is not humanity in the abstract, but whether the client is behaving in ways the site can support.
There’s a fundamental tension in how we govern access on the Internet: decentralized, anonymous, accountable — pick two.
Fully decentralized + anonymous means no accountability. A blocked client can spawn a new account without impact on its reputation. This implies that origins have to invest more to manage their resources. This is the default of the Web.
Decentralized + accountable means everyone knows who you are, which works for certain use cases but has clear drawbacks. Think OAuth mechanisms such as “Log in with”, which requires account registration and revealing activity to a third party.
Anonymous + accountable likely requires governance, rules, and enforcement. No widely deployed system achieves both properties for the same actor. The closest precedent is the Web PKI, where governance (CA policies, Certificate Transparency) holds servers accountable. When that governance fails, there are consequences. No equivalent exists today for the client side.
Current tools build on elements from that first space to strive for the second: TLS fingerprints, IP addresses, robots.txt. They attempt accountability, but only hold as long as the derived fingerprints remain stable.
The important distinctions are what, not who
For a website owner deciding how to handle incoming traffic, the meaningful distinction isn’t necessarily bots vs. humans. It’s about balancing the origin’s needs to understand the traffic it receives with the clients’ needs to preserve their privacy.
Platforms and services that want to be identifiable
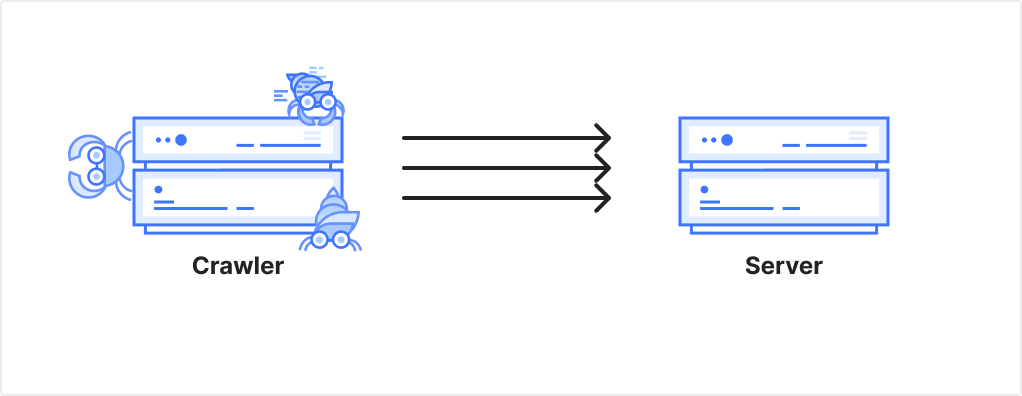
Figure 5: A crawler makes multiple request to a server
Some traffic comes from known operators making high volumes of requests: search engine crawlers, cloud platforms, enterprise infrastructure. These actors often have low privacy expectations. They’re infrastructure making millions of requests from identifiable sources. The ability to identify the source of a request helps to mitigate misjudgment if an infrastructure provider is sending you too many requests or accessing pages it should not. Self-identification is one of the principles for responsible AI bots we proposed. It is based on these principles that Cloudflare operates its URL scanner for Radar, or how we expose crawling capabilities.
For this traffic, identity works. More precisely, some operators can tolerate attributable requests because reliable access is worth it. Web Bot Auth using HTTP Message Signatures allow operators to cryptographically sign their requests. OpenAI, Google, Cloudflare, or AWS, for example, sign requests originating from their platforms. Origins can verify “this request really came from the platform infrastructure” without relying on IP ranges or User-Agent strings.
Humans and other end-users rightfully have expectations other than being identifiable, to preserve anonymity without sacrificing their access and quality of experience.
Distributed traffic that needs anonymity
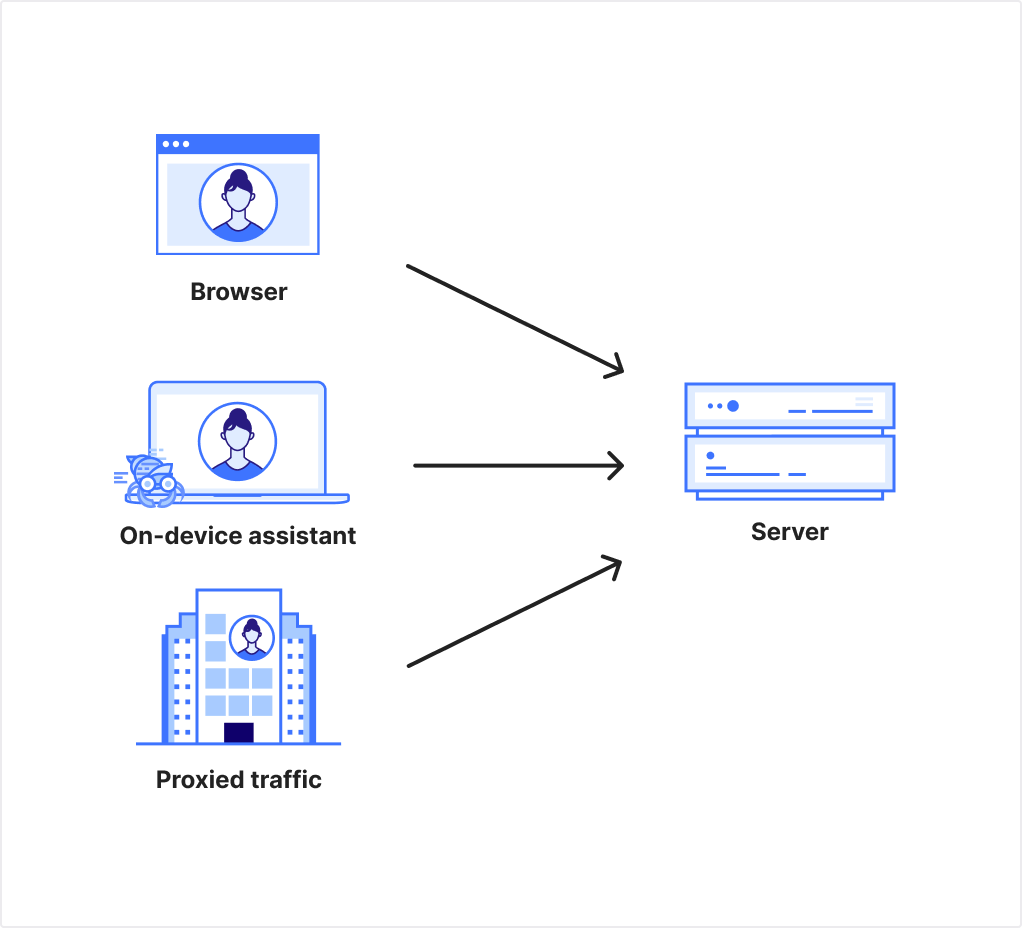
Figure 6: Three distinct browsers make a request to a server. One is operated by a human, one by an on-device assistant, and one is proxied through a corporate proxy.
Other traffic comes from many sources, each making relatively few requests. This includes humans browsing the web, researchers doing measurements, scrapers using residential proxies, and increasingly, AI assistants acting on humans’ behalf.
And increasingly the distinction between bots and humans is moot. There is no meaningful difference between the AI assistant booking concert tickets and the human who would have done so manually. Both are distributed. Both need anonymity. In each case, an origin would want to create less friction for users who wish to use the service as intended, rather than abuse it.
Identity could work. To replace the old assumption we had for IP addresses, it should provide a unique, verifiable set of attributes tied to a specific client, proven through an account login, an email address, or a hardware key. However, it implies the need to present this identity when accessing websites. It also undermines privacy.
We want to build modern solutions that prove behavior without proving identity.
Anonymous credentials for the Web
Since 2019, clients accessing websites via Cloudflare have been able to provide such proof of behavior, by sending a privacy token along with their request. This is due to Cloudflare’s early support for Privacy Pass. Privacy Pass, as standardised in RFC 9576, RFC 9578, lets a client carry an issuer-backed proof of some prior check, such as having solved a challenge, without turning that result into a stable identifier. It defines tokens that are unlinkable with any prior visit, request, or session.
This matters because it offers a different model from fingerprinting. Instead of collecting passive signals, the server can ask the client for an active privacy-preserving signal.
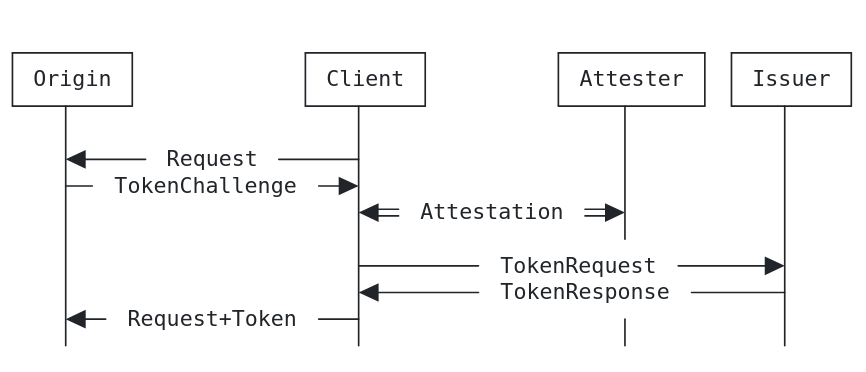
Figure 7: Privacy Pass Redemption and Issuance Protocol Interaction from Section 3.1 of RFC 9576
The RFC highlights four roles. The issuer trusts one or more attesters to perform some checks before issuing credentials (tokens in the RFC case). The client holds these credentials and decides when to present them, within the right scope. The origin remains in control of which issuers it trusts and what each presentation means. This does not remove abuse or policy questions, it simply provides clients and servers with a privacy-preserving way to handle them.
The system is simple, but it also has bounds: it does not, for example, allow for dynamic rate limits. If a client is issued 100 tokens, and starts consuming too many resources after the first or second session, there’s no way to invalidate the remaining tokens that were previously issued.
In addition, because of the unlinkability property, it’s hard for new issuers to emerge. There is no feedback mechanism that an origin can provide regarding the quality of the signal an issuer token conveys.
Finally, there’s a 1:1 relationship between the number of tokens that an issuer provides, and the number of unlinkable presentations that can be made with those tokens when they are redeemed: one token per presentation. Ideally, we would like a system in which the client contacts an issuer once and can later make multiple presentations scoped to a particular origin context. That points toward user agents holding vouched credentials and presenting proofs derived from them, rather than repeatedly acquiring single-use tokens.
With ACT, for instance, clients can prove something like “I have a good history with this service” without revealing “I am this user.” ACT preserves unlinkability between presentations at the protocol level, which is the key cryptographic property here. Even in the joint issuer-origin deployment model in Section 4.3 of RFC 9576, the protocol is designed so that token issuance and presentation are not directly linkable. That does not eliminate correlation through other layers such as IP addresses, cookies, account state, or timing. The same properties can be provided using standardized VOPRF and BlindRSA primitives within the reverse flow framework that ACT implements.
A successful ecosystem needs to be an open issuer ecosystem. In practice, that means more than saying anyone can mint credentials. Origins need to be able to decide which issuers to trust. User agents need a consistent way to present what is being requested. The ecosystem also needs ways for issuers to establish reputation and for relying parties to stop trusting low-quality issuers. No single gatekeeper should control participation.
To make this work, there needs to be a protocol and client API that works across browsers and other user agents. It has to be simple to deploy, clear to users, and narrow enough that browsers can place limits on abusive proof requests rather than merely surfacing them.
The trajectory if we do nothing
Website owners are already reacting to the disruption caused by emerging clients. This is partly caused by large-scale scraping and model training, and also by user agents acting in ways sites did not anticipate. Websites, therefore, have asked for more technical means to block AI crawlers and associated tools. In an ecosystem where the lines between bots and humans are increasingly blurred, the measures we have today will become less effective on their own.
If those measures aren’t effective, we can expect sites to pivot: requiring an account to see any content, or tying access to a stable identifier. This means no more ad-supported login-free articles, no more “three free articles a month.” Other content businesses may move away from the Web completely, offering their data and services directly to AI vendors for a fee, or within walled gardens operated by large platforms.
These outcomes are bad. Everyone benefits from the open access to information that the Web offers. It is not that all sites will make these choices. There are many reasons for offering content online, and not all of them are commercial. But if enough sites do, they change what “normal” is on the Web to be something worse.
That matters because the open Web is an environment in which different clients can gather information from different sources without relying on a handful of players. We also benefit from having a diversity of sources of information. On a Web where access to information is largely mediated through a small handful of companies, we put too much power into too few hands. The result is not just more friction for anonymous clients, but a more brittle Internet with fewer ways for publishers to meet users.
Anonymous authentication brings some risk, too
We should be clear about what we’re building. Infrastructure for proving properties can become infrastructure for requiring properties. Anonymous credentials are meant to prove something about their holder; for example, “I solved a challenge” or “I have not exceeded a rate limit.” But a system that can prove any single attribute is also capable of proving other attributes, which is a source of concern.
Today, presenting a Privacy Pass token may convey “solved a CAPTCHA”. Tomorrow, the same systems could prove entirely different attributes. For instance, issuing tokens only to devices that “have device attestation” excludes older devices and their users. Similarly, requiring attributes such as “has an Apple or Google account” excludes users of non-mainstream platforms.
Once the infrastructure exists to verify anonymous proofs, what gets proven can expand. We need to make sure this does not gate access to the Internet.
Why we should build it anyway
Gates already exist. Platforms increasingly require identity. Websites are blocking traffic coming from shared proxies. The question isn’t whether gates will appear, it’s whether the user remains in control of their privacy.
As we’ve discussed, bot management requires some signals to be shared. The alternatives to anonymous proofs are worse. Without the ability to prove attributes anonymously, every gate requires fingerprints: retry from a specific browser, link your account, don’t use a VPN. These may not even be options to people, such as the ones which have no idea their connections are proxied.
Privacy-preserving credentials do not remove the need for trust or policy. They can make those demands more explicit and less pervasive. Unlike fingerprints, proofs are explicit. Users can see what is being asked, and clients such as web browsers and AI assistants can help enforce consent.
To decide, use this guardrail
There is a simple test to evaluate the next methods for the Internet that serves everyone: do the methods allow anyone, from anywhere in the world, to build their own device, their own browser, use any operating system, and get access to the Web. If that property cannot hold, if device attestation from specific manufacturers becomes the only viable signal, we should stop.
This means we need to foster an open issuer ecosystem, where no single gatekeeper decides who can participate. In the rate limit trilemma, decentralization is mandatory on the open Web. We don’t yet know fully how to build it, but we know we need to foster it.
A new balance
Until now the Web has largely been in balance. Some aspects may have been a happy accident, while others could have been inevitable. For many end users and publishers, it worked because the Web stayed open enough to support a variety of clients accessing a similar variety of resources.
That balance is at risk. Privacy-preserving primitives for the Web are one attempt to build a different outcome: privacy-preserving, open, accountable. It is not guaranteed to succeed. But it is better than waiting.
If you are interested in tracking and participating, this work happens in the open at the IETF and at the W3C. We believe the existing places where people gathered to shape the Web of today are the best places to design the Web of tomorrow.
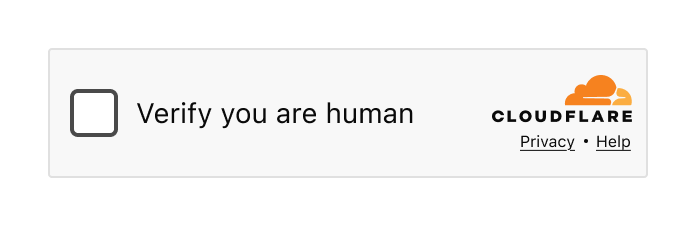
You’ve seen it. Maybe you didn’t register it consciously, but you’ve seen it. That little widget asking you to verify you’re human. That full-page security check before accessing a website. If you’ve spent any time on the Internet, you’ve encountered Cloudflare’s Turnstile widget or Challenge Pages — likely more times than you can count.
The Turnstile widget – a familiar sight across millions of websites
When we say that a large portion of the Internet sits behind Cloudflare, we mean it. Our Turnstile widget and Challenge Pages are served 7.67 billion times every single day. That’s not a typo. Billions. This might just be the most-seen user interface on the Internet.
And that comes with enormous responsibility.
Designing a product with billions of eyeballs on it isn’t just challenging — it requires a fundamentally different approach. Every pixel, every word, every interaction has to work for someone’s grandmother in rural Japan, a teenager in São Paulo, a visually impaired developer in Berlin, and a busy executive in Lagos. All at the same time. In moments of frustration.
Today we’re sharing the story of how we redesigned Turnstile and Challenge Pages. It’s a story told in three parts, by three of us: the design process and research that shaped our decisions (Leo), the engineering challenge of deploying changes at unprecedented scale (Ana), and the measurable impact on billions of users (Marina).
Let’s start with how we approached the problem from a design perspective.
Part 1: The design process
The problem
Let’s be honest: nobody likes being asked to prove they’re human. You know you’re human. I know I’m human. The only one who doesn’t seem convinced is that little widget standing between you and the website you’re trying to access. At best, it’s a minor inconvenience. At worst? You’ve probably wanted to throw your computer out the window in a fit of rage. We’ve all been there. And no one would blame you.
Turnstile integrated into a login flow
As the world warms up to what appears to be an inevitable AI revolution, the need for security verification is only increasing. At Cloudflare, we’ve seen a significant rise in bot attacks — and in response, organizations are investing more heavily in security measures. That means more challenges being issued to more end users, more often.
The numbers tell the story:
2023: 2.14B daily
2024: 3B daily
2025: 5.35B daily
That’s a 58.1% average increase in security checks, year over year. More security checks mean more opportunities for end user frustration. The more companies integrate these verification systems to protect themselves and their customers, the higher the chance that someone, somewhere, is going to have a bad experience.
We knew it was time to take a hard look at our flagship products and ask ourselves: Are we doing right by the billions of people who encounter these experiences? Are we fulfilling our mission to build a better Internet — not just a more secure one, but a more human one?
The answer, we discovered, was: we could do better.
The design audit
Before redesigning anything, we needed to understand what we were working with. We started by conducting a comprehensive audit of every state, every error message, and every interaction across both Turnstile and Challenge Pages.
What we found wasn’t the best.
The state of inconsistency in the Turnstile widget. Multiple states with no unified approach
The inconsistencies were glaring. We had no unified approach across the multitude of different error scenarios. Some messages were overly verbose and technical (“Your device clock is set to a wrong time or this challenge page was accidentally cached by an intermediary and is no longer available”). Others were too vague to be helpful (“Timed out”). The visual language varied wildly — different layouts, different hierarchies, different tones of voice.
We also examined the feedback we’d received online. Social media, support tickets, community forums — we read it all. The frustration was palpable, and much of it was avoidable.
Take our feedback mechanism, for example. We offered users feedback options like “The widget sometimes fails” versus “The widget fails all the time.” But what’s the difference, really? And how were they supposed to know how often it failed? We were asking users to interpret ambiguous options during their most frustrated moments. The more we left open to interpretation, the less useful the feedback became — and the more frustration we saw across social channels.
The previous feedback screen: “The widget sometimes fails” vs “The widget fails all the time” — what’s the difference?
Our Challenge Pages — the full-page security blocks that appear when we detect suspicious activity or when site owners have heightened security settings — had similar issues. Some states were confusing. Others used too much technical jargon. Many failed to provide actionable guidance when users needed it most.
The state of inconsistency on the Challenge pages. Multiple states with no unified approach
The audit was humbling. But it gave us a clear picture of where we needed to focus.
Mapping the user journey
To design better experiences, we first needed to understand every possible path a user could take. What was the happy path? Was there even one? And what were the unhappy paths that led to escalating frustration?
Mapping the complete user journey — from initial encounter through error scenarios, with sentiment tracking
This was a true cross-functional effort. We worked closely with engineers like Ana who knew the technical ins and outs of every edge case, and with Marina on the product side who understood not just how the product worked, but how users felt about it — the love and the hate we’d see online.
We have some of the smartest people working on bot protection at Cloudflare. But intelligence and clarity aren’t the same thing. There’s a delicate balance between technical complexity and user simplicity. Only when these two dance together successfully can we communicate information in a way that actually makes sense to people.
And here’s the thing: the messaging has to work for everyone. A person of any age. Any mental or physical capability. Any cultural background. Any level of technical sophistication. That’s what designing at scale really means — you can’t ignore edge cases, since, at such scale, they are no longer edge cases.
Establishing a unified information architecture
One of the most influential books in UX design is Steve Krug’s Don’t Make Me Think. The core principle is simple: every moment a user spends trying to interpret, understand, or decode your interface is a moment of friction. And friction, especially in moments of frustration, leads to abandonment.
Our audit revealed that we were asking users to think far too much. Different pieces of information occupied the same space in the UI across different states. There was no consistent visual hierarchy. Users encountering an error state in Turnstile would find information in a completely different place than they would on a Challenge Page.
We made a fundamental decision: one information architecture to rule them all.
Visual diagram displaying a unified information architecture with a consistent structure across Turnstile widget and Challenge pages
Both Turnstile and Challenge Pages would now follow the same structural pattern. The same visual hierarchy. The same placement for actions, for explanatory text, for links to documentation.
Did this constrain our design options? Absolutely. We had to say no to a lot of creative ideas that didn’t fit the framework. But constraints aren’t the enemy of good design — they’re often its best friend. By limiting our options, we could go deeper on the details that actually mattered.
For users, the benefit is profound: they don’t need to re-learn what each piece of the UI means. Error states look consistent. Help links are always in the same place. Once you understand one state, you understand them all. That’s cognitive load reduced to a minimum — exactly where it should be during a security verification.
What user research taught us
How do you keep yourself accountable when redesigning something that billions of people see? You test. A lot.
We recruited 8 participants across 8 different countries, deliberately seeking diversity in age, digital savviness, and cultural background. We weren’t looking for tech-savvy early adopters — we wanted to understand how the redesign would work for everyone.
Our approach was rigorous: participants saw both the current experience and proposed changes, without knowing which was “old” or “new.” We counterbalanced positioning to eliminate bias. And we did not just test our new ideas, but also challenged our assumptions about what needed changing in the first place.
Two different versions of a Turnstile being tested in an A/B test
Some things didn’t need fixing
One hypothesis: should we align with competitors? Most CAPTCHA providers show “I am human” across all states. We use distinct content — “Verify you are human,” then “Verifying…,” then “Success!”
Were we overcomplicating things? We tested it head-to-head.
Our approach won decisively. For the interactivity state, “Verify you are human” scored 5 out of 8 points versus just 3 for “I am human.” For the verifying state, it was even more dramatic — 7.5 versus 0.5. Users wanted to know what was happening, not just be told what they were.
User testing results: users strongly favored our approach over the competitor-style design
This experiment didn’t ship as a feature, but it was invaluable. It gave us confidence we weren’t just being different for the sake of it. Some things were already right.
But these needed to change
The research surfaced four areas where we were failing users:
Help, not bureaucracy. When users encountered errors, we offered “Send Feedback.” In testing, they were baffled. “Who am I sending this to? The website? Cloudflare? My ISP?” More importantly, we discovered something fundamental: at the moment of maximum frustration, people don’t want to file a report — they want to fix the problem. We replaced “Send Feedback” with “Troubleshoot” — a single word that promises action rather than bureaucracy.
The problematic “Send Feedback” prompt: users didn’t know who they were sending feedback to
Attention, not alarm. We’d used red backgrounds liberally for errors. The reaction in testing was visceral — participants felt they had failed, felt powerless. Even for simple issues that would resolve with a retry, users assumed the worst and gave up. Red at full saturation wasn’t communicating “Here’s something to address.” It was communicating “You have failed, and there’s nothing you can do.” The fix: red only for icons, never for text or backgrounds.
The evolution: from the states with unclear error state description in red to much clearer and concise error communication in neutral-color text.
Scannable, not verbose. We’d tried to be thorough, explaining errors in technical detail. It backfired. Non-technical users found it alienating. Technical users didn’t need it. Everyone was trying to read it in the tiny real estate of a widget. The lesson: less is more, especially in constrained spaces during stressful moments.
Accessible to everyone. Our audit revealed 10px fonts in some states. Grey text that technically met AA (at least 4.5:1 for normal text and 3:1 for large text) compliance but was difficult to read in practice. “Technically compliant” isn’t good enough when you’re serving the entire Internet.
We set a clear goal: to meet the WCAG 2.2 AAA standard— the highest and most stringent level of web accessibility compliance, designed to make content accessible to the broadest range of users, including those with severe disabilities. Throughout the redesign, when visual consistency conflicted with readability, readability won. Every time.
This extended beyond vision. We designed for screen reader users, keyboard-only navigators, and people with color vision variations — going beyond what automated compliance tools can catch.
And accessibility isn’t just about impairments — it’s about language. What fits in English, overflows in German. What’s concise in Spanish is ambiguous in Japanese. Supporting over 40 languages forced us to radically simplify. The same “Unable to connect to website / Troubleshoot” pattern now works across English, Bulgarian, Danish, German, Greek, Japanese, Indonesian, Russian, Slovak, Slovenian, Serbian, Filipino, and many more.
The redesigned error state across 12 languages — consistent layout despite varying text lengths
Final redesign
So what did we actually ship?
First, let’s talk about what we didn’t change. The happy path — “Verify you are human” → “Verifying…” → “Success!” — tested exceptionally well. Users understood what was happening at each stage. The distinct content for each state, which we’d worried might be overcomplicating things, was actually our competitive advantage.
The happy path: Verify you are human → Verifying → Success! These states tested well and remained largely unchanged
But for the states that needed work, we made significant changes guided by everything we learned.
Simplified, scannable content
We radically reduced the amount of text in error states. Instead of verbose explanations like “Your device clock is set to a wrong time or this challenge page was accidentally cached by an intermediary and is no longer available,” we now show:
A clear, simple state name (e.g., “Incorrect device time”)
A prominent “Troubleshoot” link
That’s it. The detailed guidance now lives in a dedicated modal screen that opens when users need it — giving them room to actually read and follow troubleshooting steps.
The troubleshooting modal: detailed guidance when users need it, without cluttering the widget
The troubleshooting modal provides context (“This error occurs when your device’s clock or calendar is inaccurate. To complete this website’s security verification process, your device must be set to the correct date and time in your time zone.”), numbered steps to try, links to documentation, and — only after the user has tried to resolve the issue — an option to submit feedback to Cloudflare. Help first, feedback second.
AAA accessibility compliance
Every state now meets WCAG 2.2 AAA standards for contrast and readability. Font sizes have established minimums. Interactive elements are clearly focusable and properly announced by screen readers.
Unified experience across Turnstile and Challenge pages
Whether users encounter the compact Turnstile widget or a full Challenge Page, the information architecture is now consistent. Same hierarchy. Same placement. Same mental model.
Challenge Pages now follow a clean structure: the website name and favicon at the top, a clear status message (like “Verification successful” or “Your browser is out of date”), and actionable guidance below. No more walls of orange or red text. No more technical jargon without context.
Re-designed Challenge page states with clear troubleshooting instructions.
Validated across languages
Every piece of content was tested in over 40 supported languages. Our process involved three layers of validation:
Initial design review by the design team
Professional translation by our qualified vendor
Final review by native-speaking Cloudflare employees
This wasn’t just about translation accuracy — it was about ensuring the visual design held up when content length varied dramatically between languages.
The complete picture
The result is a security verification experience that’s clearer, more accessible, less frustrating, and — crucially — just as secure. We didn’t compromise on protection to improve the experience. We proved that good design and strong security aren’t in conflict.
Re-designed Turnstile widgets on the left and a re-designed Challenge page on the right
But designing the experience was only half the battle. Shipping it to billions of users? That’s where Ana comes in.
Part 2: Shipping to billions
Beyond centering a div
Some may say the hardest part of being a Frontend Engineer is centering a div. In reality, the real challenge often lies much deeper, especially when working close to the platform primitives. Building a critical piece of Internet infrastructure using native APIs forces you to think differently about UI development, tradeoffs, and long-term maintainability.
In our case, we use Rust to handle the UI for both the Turnstile widget and the Challenge page. This decision brought clear benefits in terms of safety and consistency across platforms, but it also increased frontend complexity. Many of us are used to the ergonomics of modern frameworks like React, where common UI interactions come almost for free. Working with Rust meant reimplementing even simple interactions using lower level constructs like document.getElementById, createElement, and appendChild.
On top of that, compile times and strict checks naturally slowed down rapid UI iteration compared to JavaScript based frameworks. Debugging was also more involved, as the tooling ecosystem is still evolving. These constraints pushed us to be more deliberate, more thoughtful, and ultimately more disciplined in how we approached UI development.
Small visual changes, big global impact
What initially looked like small visual tweaks such as padding adjustments or alignment changes quickly revealed a much bigger challenge: internationalization.
Once translations were available, we had to ensure that content remained readable and usable across 38 languages and 16 different UI states. Text length variability alone required careful design decisions. Some translations can be 30 to 300 percent longer than English. A short English string like “Stuck?” becomes “Tidak bisa melanjutkan?” in Indonesian or “Es geht nicht weiter?” in German, dramatically changing layout requirements.
Right-to-left language support added another layer of complexity. Supporting Arabic, Persian or Farsi, and Hebrew meant more than flipping text direction. Entire layouts had to be mirrored, including alignment, navigation patterns, directional icons, and animation flows. Many of these elements are implicitly designed with left-to-right assumptions, so we had to revisit those decisions and make them truly bidirectional.
Ordered lists also required special care. Not every culture uses the Western 1, 2, 3 numbering system, and hardcoding numeric sequences can make interfaces feel foreign or incorrect. We leaned on locale-aware numbering and fully translatable list formats to ensure ordering felt natural and culturally appropriate in every language.
Building confidence through testing
As we started listing action points in feedback reports, correctness became even more critical. Every action needed to render properly, trigger the right flow, and behave consistently across states, languages, and edge cases.
To get there, we invested heavily in testing. Unit tests helped us validate logic in isolation, while end-to-end tests ensured that new states and languages worked as expected in real scenarios. This testing foundation gave us confidence to iterate safely, prevented regressions, and ensured that feedback reports remained reliable and actionable for users.
The outcome
What began as a set of technical constraints turned into an opportunity to build a more robust, inclusive, and well-tested UI system. Working with fewer abstractions and closer to the browser primitives forced us to rethink assumptions, improve our internationalization strategy, and raise the overall quality bar.
The result is not just a solution that works, but one we trust. And that trust is what allows us to keep improving, even when centering a div turns out to be the easy part.
Part 3: The impact
Designing for billions of people is a responsibility we take seriously. At this scale, it is essential to leverage measurable data to tell us the real impact of our design choices. As we prepare to roll out these changes, we are focusing on five key metrics that will tell us if we’ve truly succeeded in making the Internet’s most-seen UI more human.
1. Challenge Completion Rate
Our primary north star is the Challenge Solve Rate: the percentage of issued challenges that are successfully completed. By moving away from technical jargon like “intermediary caching” and toward simple, actionable labels like “Incorrect device time,” we expect a significant uptick in CSR. A higher CSR doesn’t mean we’re being easier on bots; it means we’re removing the hurdles that were accidentally tripping up legitimate human users.
2. Time to Complete
Every second a user spends on a challenge page is a second they aren’t getting the information that they need. Our research showed that users were often paralyzed by choice when seeing a wall of red text. With our new scannable, neutral-color design, we are tracking Time to Complete to ensure users can identify and resolve issues in seconds rather than minutes.
3. Abandonment Rate Changes
In the past, our liberal use of “saturated red” caused a visceral reaction: users felt they had failed and simply gave up. By reserving red only for icons and using a unified architecture, we aim to reduce Abandonment Rates. We want users to feel empowered to click Troubleshoot rather than feeling powerless and clicking away.
4. Support Ticket Volume
One of the bigger shifts from a product perspective is our new Troubleshooting Modal. By providing clear, numbered steps directly within the widget, we are building self-service support into the UI. We expect this to result in a measurable decrease in support ticket volume for both our customers and our own internal teams.
5. Social Sentiment
We know that security challenges are rarely loved, but they shouldn’t be hated because they are confusing. We are monitoring Social Sentiment across community forums, feedback reports, and social channels to see if the conversation shifts from “this widget is broken” to “I had an issue, but I fixed it”.
As a Product Manager, my goal is often invisible security — the best challenge is the one the user never sees. But when a challenge must be seen, it should be an assistant, not a bouncer. This redesign proves that AAA accessibility and high-security standards aren’t in competition; they are two sides of the same coin. By unifying the architecture of Turnstile and Challenge Pages, we’ve built a foundation that allows us to iterate faster and protect the Internet more humanely than ever before.
Looking ahead
This redesign is a foundation, not a finish line.
We’re continuing to monitor how users interact with the new experience, and we’re committed to iterating based on what we learn. The feedback mechanisms we’ve built into the new design — the ones that actually help users troubleshoot, rather than just asking them to report problems — will give us richer insights than we’ve ever had before.
We’re also watching how the security landscape evolves. As bot attacks grow more sophisticated, and as AI continues to blur the line between human and automated behavior, the challenge of verification will only get harder. Our job is to stay ahead — to keep improving security without making the human experience worse.
If you encounter the new Turnstile or Challenge Pages and have feedback, we want to hear it. Reach out through our community forums or use the feedback mechanisms built into the experience itself.
As bots and agents start cryptographically signing their requests, there is a growing need for website operators to learn public keys as they are setting up their service. I might be able to find the public key material for well-known fetchers and crawlers, but what about the next 1,000 or next 1,000,000? And how do I find their public key material in order to verify that they are who they say they are? This problem is called discovery.
We share this problem with Amazon Bedrock AgentCore, a comprehensive agentic platform to build, deploy and operate highly capable agents at scale, and their AgentCore Browser, a fast, secure, cloud-based browser runtime to enable AI agents to interact with websites at scale. The AgentCore team wants to make it easy for each of their customers to sign their own requests, so that Cloudflare and other operators of CDN infrastructure see agent signatures from individual agents rather than AgentCore as a monolith. (Note: this method does not identify individual users.) In order to do this, Cloudflare needed a way to ingest and register the public keys of AgentCore’s customers at scale.
In this blog post, we propose a registry of bots and agents as a way to easily discover them on the Internet. We also outline how Web Bot Auth can be expanded with a registry format. Similar to IP lists that can be authored by anyone and easily imported, the registry format is a list of URLs at which to retrieve agent keys and can be authored and imported easily.
We believe such registries should foster and strengthen an open ecosystem of curators that website operators can trust.
A need for more trustworthy authentication
In May, we introduced a protocol proposal called Web Bot Auth, which describes how bot and agent developers can cryptographically sign requests coming from their infrastructure.
There have now been multiple implementations of the proposed protocol, from Vercel to Shopify to Visa. It has been actively discussed and contributions have been made. Web Bot Auth marks a first step towards moving from brittle identification, like IPs and user agents, to more trustworthy cryptographic authentication. However, like IP addresses, cryptographic keys are a pseudonymous form of identity. If you operate a website without the scale and reach of large CDNs, how do you discover the public key of known crawlers?
The first protocol proposal suggested one approach: bot operators would provide a newly-defined HTTP header Signature-Agent that refers to an HTTP endpoint hosting their keys. Similar to IP addresses, the default is to allow all, but if a particular operator is making too many requests, you can start taking actions: increase their rate limit, contact the operator, etc.
With all that in mind, we come to the following problem. How can Cloudflare ensure customers have control over the traffic they want to allow, with sensible defaults, while fostering an open curation ecosystem that doesn’t lock in customers or small origins?
Such an ecosystem exists for lists of IP addresses (e.g. avestel-bots-ip-lists) and robots.txt (e.g. ai-robots-txt). For both, you can find canonical lists on the Internet to easily configure your website to allow or disallow traffic from those IPs. They provide direct configuration for your nginx or haproxy, and you can use it to configure your Cloudflare account. For instance, I could import the robots.txt below:
User-agent: MyBadBot
Disallow: /
This is where the registry format comes in, providing a list of URLs pointing to Signature Agent keys:
# AI Crawler
https://chatgpt.com/.well-known/http-message-signatures-directory
https://autorag.ai.cloudflare.com/.well-known/http-message-signatures-directory

# Test signature agent card
https://http-message-signatures-example.research.cloudflare.com/.well-known/http-message-signatures-directory
And that’s it. A registry could contain a list of all known signature agents, a curated list for academic research agents, for search agents, etc.
Anyone can maintain and host these lists. Similar to IP or robots.txt list, you can host such a registry on any public file system. This means you can have a repository on GitHub, put the file on Cloudflare R2, or send it as an email attachment. Cloudflare intends to provide one of the first instances of this registry, so that others can contribute to it or reference it when building their own.
Learn more about an incoming request
Knowing the Signature-Agent is great, but not sufficient. For instance, to be a verified bot, Cloudflare requires a contact method, in case requests from that infrastructure suddenly fail or change format in a way that causes unexpected errors upstream. In fact, there is a lot of information an origin might want to know: a name for the operator, a contact method, a logo, the expected crawl rate, etc.
Therefore, to complement the registry format, we have proposed a signature-agent card format that extends the JWKS directory (RFC 7517) with additional metadata. Similar to an old-fashioned contact card, it includes all the important information someone might want to know about your agent or crawler.
We provide an example below for illustration. Note that the fields may change: introducing jwks-uri, logo being more descriptive, etc.
Amazon Bedrock AgentCore, an agentic platform for building and deploying AI agents at scale, adopted Web Bot Auth for its AgentCore Browser service (learn more in their post). AgentCore Browser intends to transition from a service signing key that is currently available in their public preview, to customer-specific keys, once the protocol matures. Cloudflare and other operators of origin protection service will be able to see and validate signatures from individual AgentCore customers rather than AgentCore as a whole.
Cloudflare also offers a registry for bots and agents it trusts, provided through Radar. It uses the registry format to allow for the consumption of bots trusted by Cloudflare on your server.
You can use these registries today – we’ve provided a demo in Go for Caddy server that would allow us to import keys from multiple registries. It’s on cloudflare/web-bot-auth. The configuration looks like this:
:8080 {
    route {
        # httpsig middleware is used here
        httpsig {
            registry "http://localhost:8787/test-registry.txt"
            # You can specify multiple registries. All tags will be checked independantly
            registry "http://example.test/another-registry.txt"
        }

        # Responds if signature is valid
        handle {
            respond "Signature verification succeeded!" 200
        }
    }
}
There are several reasons why you might want to operate and curate a registry leveraging the Signature Agent Card format:
Monitor incoming Signature-Agents. This should allow you to collect signature-agent cards of agents reaching out to your domain.
Import them from existing registries, and categorize them yourself. There could be a general registry constructed from the monitoring step above, but registries might be more useful with more categories.
Establish direct relationships with agents. Cloudflare does this for itsbot registry for instance, or you might use a public GitHub repository where people can open issues.
Learn from your users. If you offer a security service, allowing your customers to specify the registries/signature-agents they want to let through allows you to gain valuable insight.
Moving forward
As cryptographic authentication for bots and agents grows, the need for discovery increases.
With the introduction of a lightweight format and specification to attach metadata to Signature-Agent, and curate them in the form of registries, we begin to address this need. The HTTP Message Signature directory format is being expanded to include some self-certified metadata, and the registry maintains a curation ecosystem.
Down the line, we predict that clients and origins will choose the signature-agent they trust, use a common format to migrate their configuration between CDN providers, and rely on a third-party registry for curation. We are working towards integrating these capabilities into our bot management and rule engines.
IP addresses have historically been treated as stable identifiers for non-routing purposes such as for geolocation and security operations. Many operational and security mechanisms, such as blocklists, rate-limiting, and anomaly detection, rely on the assumption that a single IP address represents a cohesive, accountableentity or even, possibly, a specific user or device.
But the structure of the Internet has changed, and those assumptions can no longer be made. Today, a single IPv4 address may represent hundreds or even thousands of users due to widespread use of Carrier-Grade Network Address Translation (CGNAT), VPNs, and proxymiddleboxes. This concentration of traffic can result in significant collateral damage – especially to users in developing regions of the world – when security mechanisms are applied without taking into account the multi-user nature of IPs.
This blog post presents our approach to detecting large-scale IP sharing globally. We describe how we build reliable training data, and how detection can help avoid unintentional bias affecting users in regions where IP sharing is most prevalent. Arguably it’s those regional variations that motivate our efforts more than any other.
Why this matters: Potential socioeconomic bias
Our work was initially motivated by a simple observation: CGNAT is a likely unseen source of bias on the Internet. Those biases would be more pronounced wherever there are more users and few addresses, such as in developing regions. And these biases can have profound implications for user experience, network operations, and digital equity.
The reasons are understandable for many reasons, not least because of necessity. Countries in the developing world often have significantly fewer available IPs, and more users. The disparity is a historical artifact of how the Internet grew: the largest blocks of IPv4 addresses were allocated decades ago, primarily to organizations in North America and Europe, leaving a much smaller pool for regions where Internet adoption expanded later.
To visualize the IPv4 allocation gap, we plot country-level ratios of users to IP addresses in the figure below. We take online user estimates from the World Bank Group and the number of IP addresses in a country from Regional Internet Registry (RIR) records. The colour-coded map that emerges shows that the usage of each IP address is more concentrated in regions that generally have poor Internet penetration. For example, large portions of Africa and South Asia appear with the highest user-to-IP ratios. Conversely, the lowest user-to-IP ratios appear in Australia, Canada, Europe, and the USA — the very countries that otherwise have the highest Internet user penetration numbers.
The scarcity of IPv4 address space means that regional differences can only worsen as Internet penetration rates increase. A natural consequence of increased demand in developing regions is that ISPs would rely even more heavily on CGNAT, and is compounded by the fact that CGNAT is common in mobile networks that users in developing regions so heavily depend on. All of this means that actions known to be based on IP reputation or behaviour would disproportionately affect developing economies.
Cloudflare is a global network in a global Internet. We are sharing our methodology so that others might benefit from our experience and help to mitigate unintended effects. First, let’s better understand CGNAT.
When one IP address serves multiple users
Large-scale IP address sharing is primarily achieved through two distinct methods. The first, and more familiar, involves services like VPNs and proxies. These tools emerge from a need to secure corporate networks or improve users’ privacy, but can be used to circumvent censorship or even improve performance. Their deployment also tends to concentrate traffic from many users onto a small set of exit IPs. Typically, individuals are aware they are using such a service, whether for personal use or as part of a corporate network.
Separately, another form of large-scale IP sharing often goes unnoticed by users: Carrier-Grade NAT (CGNAT). One way to explain CGNAT is to start with a much smaller version of network address translation (NAT) that very likely exists in your home broadband router, formally called a Customer Premises Equipment (or CPE), which translates unseen private addresses in the home to visible and routable addresses in the ISP. Once traffic leaves the home, an ISP may add an additional enterprise-level address translation that causes many households or unrelated devices to appear behind a single IP address.
The crucial difference between large-scale IP sharing is user choice: carrier-grade address sharing is not a user choice, but is configured directly by Internet Service Providers (ISPs) within their access networks. Users are not aware that CGNATs are in use.
The primary driver for this technology, understandably, is the exhaustion of the IPv4 address space. IPv4’s 32-bit architecture supports only 4.3 billion unique addresses — a capacity that, while once seemingly vast, has been completely outpaced by the Internet’s explosive growth. By the early 2010s, Regional Internet Registries (RIRs) had depleted their pools of unallocated IPv4 addresses. This left ISPs unable to easily acquire new address blocks, forcing them to maximize the use of their existing allocations.
While the long-term solution is the transition to IPv6, CGNAT emerged as the immediate, practical workaround. Instead of assigning a unique public IP address to each customer, ISPs use CGNAT to place multiple subscribers behind a single, shared IP address. This practice solves the problem of IP address scarcity. Since translated addresses are not publicly routable, CGNATs have also had the positive side effect of protecting many home devices that might be vulnerable to compromise.
CGNATs also create significant operational fallout stemming from the fact that hundreds or even thousands of clients can appear to originate from a single IP address. This means an IP-based security system may inadvertently block or throttle large groups of users as a result of a single user behind the CGNAT engaging in malicious activity.
This isn’t a new or niche issue. It has been recognized for years by the Internet Engineering Task Force (IETF), the organization that develops the core technical standards for the Internet. These standards, known as Requests for Comments (RFCs), act as the official blueprints for how the Internet should operate. RFC 6269, for example, discusses the challenges of IP address sharing, while RFC 7021 examines the impact of CGNAT on network applications. Both explain that traditional abuse-mitigation techniques, such as blocklisting or rate-limiting, assume a one-to-one relationship between IP addresses and users: when malicious activity is detected, the offending IP address can be blocked to prevent further abuse.
In shared IPv4 environments, such as those using CGNAT or other address-sharing techniques, this assumption breaks down because multiple subscribers can appear under the same public IP. Blocking the shared IP therefore penalizes many innocent users along with the abuser. In 2015 Ofcom, the UK’s telecommunications regulator, reiterated these concerns in a report on the implications of CGNAT where they noted that, “In the event that an IPv4 address is blocked or blacklisted as a source of spam, the impact on a CGNAT would be greater, potentially affecting an entire subscriber base.”
While the hope was that CGNAT was only a temporary solution until the eventual switch to IPv6, as the old proverb says, nothing is more permanent than a temporary solution. While IPv6 deployment continues to lag, CGNAT deployments have become increasingly common, and so do the related problems.
CGNAT detection at Cloudflare
To enable a fairer treatment of users behind CGNAT IPs by security techniques that rely on IP reputation, our goal is to identify large-scale IP sharing. This allows traffic filtering to be better calibrated and collateral damage minimized. Additionally, we want to distinguish CGNAT IPs from other large-scale sharing (LSS) IP technologies, such as VPNs and proxies, because we may need to take different approaches to different kinds of IP-sharing technologies.
To do this, we decided to take advantage of Cloudflare’s extensive view of the active IP clients, and build a supervised learning classifier that would distinguish CGNAT and VPN/proxy IPs from IPs that are allocated to a single subscriber (non-LSS IPs), based on behavioural characteristics. The figure below shows an overview of our supervised classifier:
While our classification approach is straightforward, a significant challenge is the lack of a reliable, comprehensive, and labeled dataset of CGNAT IPs for our training dataset.
Detecting CGNAT using public data sources
Detection begins by building an initial dataset of IPs believed to be associated with CGNAT. Cloudflare has vast HTTP and traffic logs. Unfortunately there is no signal or label in any request to indicate what is or is not a CGNAT.
To build an extensive labelled dataset to train our ML classifier, we employ a combination of network measurement techniques, as described below. We rely on public data sources to help disambiguate an initial set of large-scale shared IP addresses from others in Cloudflare’s logs.
Distributed Traceroutes
The presence of a client behind CGNAT can often be inferred through traceroute analysis. CGNAT requires ISPs to insert a NAT step that typically uses the Shared Address Space (RFC 6598) after the customer premises equipment (CPE). By running a traceroute from the client to its own public IP and examining the hop sequence, the appearance of an address within 100.64.0.0/10 between the first private hop (e.g., 192.168.1.1) and the public IP is a strong indicator of CGNAT.
Traceroute can also reveal multi-level NAT, which CGNAT requires, as shown in the diagram below. If the ISP assigns the CPE a private RFC 1918 address that appears right after the local hop, this indicates at least two NAT layers. While ISPs sometimes use private addresses internally without CGNAT, observing private or shared ranges immediately downstream combined with multiple hops before the public IP strongly suggests CGNAT or equivalent multi-layer NAT.
Although traceroute accuracy depends on router configurations, detecting private and shared IP ranges is a reliable way to identify large-scale IP sharing. We apply this method to distributed traceroutes from over 9,000 RIPE Atlas probes to classify hosts as behind CGNAT, single-layer NAT, or no NAT.
Scraping WHOIS and PTR records
Many operators encode metadata about their IPs in the corresponding reverse DNS pointer (PTR) record that can signal administrative attributes and geographic information. We first query the DNS for PTR records for the full IPv4 space and then filter for a set of known keywords from the responses that indicate a CGNAT deployment. For example, each of the following three records matches a keyword (cgnat, cgn or lsn) used to detect CGNAT address space:
WHOIS and Internet Routing Registry (IRR) records may also contain organizational names, remarks, or allocation details that reveal whether a block is used for CGNAT pools or residential assignments.
Given that both PTR and WHOIS records may be manually maintained and therefore may be stale, we try to sanitize the extracted data by validating the fact that the corresponding ISPs indeed use CGNAT based on customer and market reports.
Collecting VPN and proxy IPs
Compiling a list of VPN and proxy IPs is more straightforward, as we can directly find such IPs in public service directories for anonymizers. We also subscribe to multiple VPN providers, and we collect the IPs allocated to our clients by connecting to a unique HTTP endpoint under our control.
Modeling CGNAT with machine learning
By combining the above techniques, we accumulated a dataset of labeled IPs for more than 200K CGNAT IPs, 180K VPNs & proxies and close to 900K IPs allocated that are not LSS IPs. These were the entry points to modeling with machine learning.
Feature selection
Our hypothesis was that aggregated activity from CGNAT IPs is distinguishable from activity generated from other non-CGNAT IP addresses. Our feature extraction is an evaluation of that hypothesis — since networks do not disclose CGNAT and other uses of IPs, the quality of our inference is strictly dependent on our confidence in the training data. We claim the key discriminator is diversity, not just volume. For example, VM-hosted scanners may generate high numbers of requests, but with low information diversity. Similarly, globally routable CPEs may have individually unique characteristics, but with volumes that are less likely to be caught at lower sampling rates.
In our feature extraction, we parse a 1% sampled HTTP requests log for distinguishing features of IPs compiled in our reference set, and the same features for the corresponding /24 prefix (namely IPs with the same first 24 bits in common). We analyse the features for each of the VPNs, proxies, CGNAT, or non LSS IP. We find that features from the following broad categories are key discriminators for the different types of IPs in our training dataset:
Client-side signals: We analyze the aggregate properties of clients connecting from an IP. A large, diverse user base (like on a CGNAT) naturally presents a much wider statistical variety of client behaviors and connection parameters than a single-tenant server or a small business proxy.
Network and transport-level behaviors: We examine traffic at the network and transport layers. The way a large-scale network appliance (like a CGNAT) manages and routes connections often leaves subtle, measurable artifacts in its traffic patterns, such as in port allocation and observed network timing.
Traffic volume and destination diversity: We also model the volume and “shape” of the traffic. An IP representing thousands of independent users will, on average, generate a higher volume of requests and target a much wider, less correlated set of destinations than an IP representing a single user.
Crucially, to distinguish CGNAT from VPNs and proxies (which is absolutely necessary for calibrated security filtering), we had to aggregate these features at two different scopes: per-IP and per /24 prefixes. CGNAT IPs are typically allocated large blocks of IPs, whereas VPNs IPs are more scattered across different IP prefixes.
Classification results
We compute the above features from HTTP logs over 24-hour intervals to increase data volume and reduce noise due to DHCP IP reallocation. The dataset is split into 70% training and 30% testing sets with disjoint /24 prefixes, and VPN and proxy labels are merged due to their similarity and lower operational importance compared to CGNAT detection.
Then we train a multi-class XGBoost model with class weighting to address imbalance, assigning each IP to the class with the highest predicted probability. XGBoost is well-suited for this task because it efficiently handles large feature sets, offers strong regularization to prevent overfitting, and delivers high accuracy with limited parameter tuning. The classifier achieves 0.98 accuracy, 0.97 weighted F1, and 0.04 log loss. The figure below shows the confusion matrix of the classification.
Our model is accurate for all three labels. The errors observed are mainly misclassifications of VPN/proxy IPs as CGNATs, mostly for VPN/proxy IPs that are within a /24 prefix that is also shared by broadband users outside of the proxy service. We also evaluate the prediction accuracy using k-fold cross validation, which provides a more reliable estimate of performance by training and validating on multiple data splits, reducing variance and overfitting compared to a single train–test split. We select 10 folds and we evaluate the Area Under the ROC Curve (AUC) and the multi-class logloss. We achieve a macro-average AUC of 0.9946 (σ=0.0069) and log loss of 0.0429 (σ=0.0115). Prefix-level features are the most important contributors to classification performance.
Users behind CGNAT are more likely to be rate limited
The figure below shows the daily number of CGNAT IP inferences generated by our CDN-deployed detection service between December 17, 2024 and January 9, 2025. The number of inferences remains largely stable, with noticeable dips during weekends and holidays such as Christmas and New Year’s Day. This pattern reflects expected seasonal variations, as lower traffic volumes during these periods lead to fewer active IP ranges and reduced request activity.
Next, recall that actions that rely on IP reputation or behaviour may be unduly influenced by CGNATs. One such example is bot detection. In an evaluation of our systems, we find that bot detection is resilient to those biases. However, we also learned that customers are more likely to rate limit IPs that we find are CGNATs.
We analyze bot labels by analyzing how often requests from CGNAT and non-CGNAT IPs are labeled as bots. Cloudflare assigns a bot score to each HTTP request using CatBoost models trained on various request features, and these scores are then exposed through the Web Application Firewall (WAF), allowing customers to apply filtering rules. The median bot rate is nearly identical for CGNAT (4.8%) and non-CGNAT (4.7%) IPs. However, the mean bot rate is notably lower for CGNATs (7%) than for non-CGNATs (13.1%), indicating different underlying distributions. Non-CGNAT IPs show a much wider spread, with some reaching 100% bot rates, while CGNAT IPs cluster mostly below 15%. This suggests that non-CGNAT IPs tend to be dominated by either human or bot activity, whereas CGNAT IPs reflect mixed behavior from many end users, with human traffic prevailing.
Interestingly, despite bot scores that indicate traffic is more likely to be from human users, CGNAT IPs are subject to rate limiting three times more often than non-CGNAT IPs. This is likely because multiple users share the same public IP, increasing the chances that legitimate traffic gets caught by customers’ bot mitigation and firewall rules.
This tells us that users behind CGNAT IPs are indeed susceptible to collateral effects, and identifying those IPs allows us to tune mitigation strategies to disrupt malicious traffic quickly while reducing collateral impact on benign users behind the same address.
A global view of the CGNAT ecosystem
One of the early motivations of this work was to understand if our knowledge about IP addresses might hide a bias along socio-economic boundaries—and in particular if an action on an IP address may disproportionately affect populations in developing nations, often referred to as the Global South. Identifying where different IPs exist is a necessary first step.
The map below shows the fraction of a country’s inferred CGNAT IPs over all IPs observed in the country. Regions with a greater reliance on CGNAT appear darker on the map. This view highlights the geodiversity of CGNATs in terms of importance; for example, much of Africa and Central and Southeast Asia rely on CGNATs.
As further evidence of continental differences, the boxplot below shows the distribution of distinct user agents per IP across /24 prefixes inferred to be part of a CGNAT deployment in each continent.
Notably, Africa has a much higher ratio of user agents to IP addresses than other regions, suggesting more clients share the same IP in African ASNs. So, not only do African ISPs rely more extensively on CGNAT, but the number of clients behind each CGNAT IP is higher.
While the deployment rate of CGNAT per country is consistent with the users-per-IP ratio per country, it is not sufficient by itself to confirm deployment. The scatterplot below shows the number of users (according to APNIC user estimates) and the number of IPs per ASN for ASNs where we detect CGNAT. ASNs that have fewer available IP addresses than their user base appear below the diagonal. Interestingly the scatterplot indicates that many ASNs with more addresses than users still choose to deploy CGNAT. Presumably, these ASNs provide additional services beyond broadband, preventing them from dedicating their entire address pool to subscribers.
What this means for everyday Internet users
Accurate detection of CGNAT IPs is crucial for minimizing collateral effects in network operations and for ensuring fair and effective application of security measures. Our findings underscore the potential socio-economic and geographical variations in the use of CGNATs, revealing significant disparities in how IP addresses are shared across different regions.
At Cloudflare we are going beyond just using these insights to evaluate policies and practices. We are using the detection systems to improve our systems across our application security suite of features, and working with customers to understand how they might use these insights to improve the protections they configure.
Our work is ongoing and we’ll share details as we go. In the meantime, if you’re an ISP or network operator that operates CGNAT and want to help, get in touch at [email protected]. Sharing knowledge and working together helps make better and equitable user experience for subscribers, while preserving web service safety and security.
Cloudflare launched fifteen years ago with a mission to help build a better Internet. Over that time the Internet has changed and so has what it needs from teams like ours. In this year’s Founder’s Letter, Matthew and Michelle discussed the role we have played in the evolution of the Internet, from helping encryption grow from 10% to 95% of Internet traffic to more recent challenges like how people consume content.
This year’s themes focused on helping prepare the Internet for a new model of monetization that encourages great content to be published, fostering more opportunities to build community both inside and outside of Cloudflare, and evergreen missions like making more features available to everyone and constantly improving the speed and security of what we offer.
We shipped a lot of new things this year. In case you missed the dozens of blog posts, here is a breakdown of everything we announced during Birthday Week 2025.
To support a diverse and open Internet, we are now sponsoring Ladybird (an independent browser) and Omarchy (an open-source Linux distribution and developer environment).
We are opening our office doors in four major cities (San Francisco, Austin, London, and Lisbon) as free hubs for startups to collaborate and connect with the builder community.
We are removing cost as a barrier for the next generation by giving students with .edu emails 12 months of free access to our paid developer platform features.
We are partnering with Coinbase to create the x402 Foundation, encouraging the adoption of the x402 protocol to allow clients and services to exchange value on the web using a common language
Our Automatic SSL/TLS system has upgraded over 6 million domains to more secure encryption modes by default and will soon automatically enable post-quantum connections.
We made our CSAM Scanning Tool easier to adopt by removing the need to create and provide unique credentials, helping more site owners protect their platforms.
Updates across Workers and beyond for a more powerful developer platform – such as support for larger and more concurrent Container images, support for external models from OpenAI and Anthropic in AI Search (previously AutoRAG), and more.
A deep-dive into how we’ve hardened the Workers runtime with new defense-in-depth security measures, including V8 sandboxes and hardware-assisted memory protection keys.
We announced the Cloudflare Email Service private beta, allowing developers to reliably send and receive transactional emails directly from Cloudflare Workers.
The TCP Connection Time (Trimean) graph shows that we are the fastest TCP connection time in 40% of measured ISPs – and the fastest across the top networks.
We are using our network’s vast performance data to tune congestion control algorithms, improving speeds by an average of 10% for QUIC traffic.
Come build with us!
Helping build a better Internet has always been about more than just technology. Like the announcements about interns or working together in our offices, the community of people behind helping build a better Internet matters to its future. This week, we rolled out our most ambitious set of initiatives ever to support the builders, founders, and students who are creating the future.
For founders and startups, we are thrilled to welcome Cohort #6 to the Workers Launchpad, our accelerator program that gives early-stage companies the resources they need to scale. But we’re not stopping there. We’re opening our doors, literally, by launching new physical hubs for startups in our San Francisco, Austin, London, and Lisbon offices. These spaces will provide access to mentorship, resources, and a community of fellow builders.
We’re also investing in the next generation of talent. We announced free access to the Cloudflare developer platform for all students, giving them the tools to learn and experiment without limits. To provide a path from the classroom to the industry, we also announced our goal to hire 1,111 interns in 2026 — our biggest commitment yet to fostering future tech leaders.
And because a better Internet is for everyone, we’re extending our support to non-profits and public-interest organizations, offering them free access to our production-grade developer tools, so they can focus on their missions.
Whether you’re a founder with a big idea, a student just getting started, or a team working for a cause you believe in, we want to help you succeed.
Until next year
Thank you to our customers, our community, and the millions of developers who trust us to help them build, secure, and accelerate the Internet. Your curiosity and feedback drive our innovation.
It’s been an incredible 15 years. And as always, we’re just getting started!
Today, we are announcing a new approach to catching bots: using models to provide behavioral anomaly detection unique to each bot management customer and stop sophisticated bot attacks.
With this per-customer approach, we’re giving every bot management customer hyper-personalized security capabilities to stop even the sneakiest bots. We’re doing this by not only making a first-request judgement call, but also by tracking behavior of bots who play the long-game and continuously execute unwanted behavior on our customers’ websites. We want to share how this service works, and where we’re focused. Our new platform has the power to fuel hundreds of thousands of unique detection suites, and we’ve heard our first target loud and clear from site owners: protect websites from the explosion of sophisticated, AI-driven web scraping.
The new arms race: the rise of AI-driven scraping
The battle against malicious bots used to be a simpler affair. Attackers used scripts that were fairly easy to identify through static, predictable signals: a request with a missing User-Agent header, a malformed method name, or traffic from a non-standard port was a clear indicator of malicious intent. However, the Internet is always evolving. As websites became more dynamic to create rich user experiences, attackers evolved their tools in response. The simple scripts of yesterday were replaced by headless browsers and automation frameworks, capable of rendering pages and mimicking human interaction with far greater fidelity.
AI has made this even trickier. The rise of Generative AI has fundamentally changed the capabilities and the motivations of attackers. The web scraping of today isn’t limited to competitive price intelligence or content aggregation, but driven by the voracious appetite of Large Language Models (LLMs) for training data.
Cloudflare’s data shows this shift in stark terms. In mid-2025, crawling for the purpose of AI model training accounted for nearly 80% of all AI bot activity on our network, a significant increase from the year prior. Modern scraping tools are now AI-powered themselves. They leverage LLMs for semantic understanding of page content, use computer vision to solve visual challenges, and employ reinforcement learning to navigate complex websites they’ve never seen before. The evolution of these bots exposes critical vulnerability in the traditional, one-size-fits-all approach to security. While global threat intelligence is immensely powerful for stopping widespread attacks, these new AI-powered scrapers are designed to blend in. They can rotate IP addresses through residential proxies, generate human-like user agents, and mimic plausible browsing patterns. A request from one of these bots might not look anomalous when compared to the trillions of requests we see across the Cloudflare network, but would appear anomalous when compared to the established patterns of legitimate users on a specific website. This means we need to build defenses against these bots from every angle we have — from the global view to specific behavior on a single application.
Globally scalable bot fingerprinting
To target specific well-known bots or bot actors, we leverage the Cloudflare network to fingerprint bots that we see behave similarly across millions of websites. Since June, Cloudflare’s bot detection security analysts have written 50 heuristics to catch bots using a variety of signals, including but not limited to HTTP/2 fingerprints and Client Hello extensions. By observing traffic on millions of websites, we establish a baseline of legitimate fingerprints of common browsers and benign devices. When a new, unique fingerprint suddenly appears across many different sites, it’s a tell-tale sign of a distributed botnet or a new automation tool, allowing our analysts to block the bot’s signature itself and neutralize the entire campaign, regardless of the thousands of different IP addresses it might use.
Recently, we also introduced detection improvements to tackle residential proxy networks and similar commercial proxies, which are used by attackers to make their bots appear as thousands of distinct real visitors, allowing them to bypass traditional security measures. The superpower of this detection improvement? Combining the vast amount of network data we see with particular client-side fingerprints obtained through the millions of challenge solves that happen across the Internet daily. Challenges have always served as an ideal mitigation action for customers who want to protect their applications without compromising real-user experience, but now they also serve as a gift that keeps on giving: in this case, feeding the Cloudflare threat detection teams a constant stream of client-side information that allows us to pattern match to determine IP addresses that are used by residential proxy networks.
This detection improvement is already ingesting data from the entire Cloudflare network, automatically catching more malicious traffic for all customers using Super Bot Fight Mode (bot protection included for Pro, Business, and all Enterprise customers) and Enterprise Bot Management. Examining 7 days of data from the time of authoring this post, we’ve observed 11 billion requests from millions of unique IP addresses that we’ve identified as connected to residential or commercial proxy networks. This is just one piece of the global detection puzzle; the existing residential proxy detection features in our MLalready catch tens of millions of requests every hour.
Hyper-personalized security: learning what’s normal for you
The new arms race against AI-powered bots necessitates a closer look — something more precise. For instance, a script that systematically scrapes every user profile on a social media site, or every product listing on an e-commerce platform, is exhibiting behavior that is fundamentally abnormal for that application, even if a standalone request appears benign. This realization is at the heart of our new strategy: to win this new arms race, defenses must become as bespoke and adaptive as the attacks they face.
To meet this challenge, we built a new, foundational platform engineered to deploy custom machine learning models for every bot management customer. We’re creating a unique defense for every application. Because each website has different traffic, the traffic that we flag as anomalous will, of course, be different for each zone — for this system, we want to be clear that data from one customer’s zone won’t be used to train the model for another customer’s use.
Announcing this as a new platform capability, rather than a single feature, is a deliberate choice. It aligns with how we’ve approached our most significant innovations, from Cloudflare Workers changing how developers build applications, to AI Gateway creating a single control plane for AI observability and security. By focusing on the platform, we tackle the scraping problems our customers are seeing today and power future detections as bot attacks become increasingly sophisticated.
Our new generation of per-customer anomaly detection is a three-step process, designed to identify malicious behavior by first understanding what constitutes legitimate traffic for each individual website and API.
Step 1: Establishing a dynamic baseline
For each customer zone, our behavioral detections ingest traffic data to build a baseline of normal activity. Rather than taking a static snapshot, our new platform ingests data to make living, continuously updated calculations of what “normal” looks like on a specific website. This approach understands seasonality, recognizes traffic spikes from legitimate marketing campaigns, and maps the typical pathways users take through a site. This approach evolves the concept of Anomaly Detection already present in our Enterprise Bot Management suite, but applies it at a far more granular and dynamic per-customer level.
Step 2: Identifying the anomalies
Once the baseline of “normal” is established, we begin the true work — identifying deviations. Because the baseline is specific to each website, the anomalies detected are highly contextual, perhaps even invisible to a global system. We can examine a few different types of websites to unpack this:
For a gaming company: A normal traffic baseline might show millions of users making frequent, rapid API calls to a matchmaking service or an in-game inventory system. A behavioral detection model trained on this baseline would immediately flag a single user making slow, methodical, sequential API calls to scrape the entire player leaderboard. This behavior, while low in volume, is a clear anomaly against the backdrop of normal gameplay patterns.
For a retail website: The normal baseline is a complex funnel of users browsing categories, viewing products, adding items to a cart, and proceeding to checkout. These detections would identify an actor that systematically visits every single product page in alphabetical order at a machine-like pace, without ever interacting with the cart or session cookies, as a significant anomaly indicative of content scraping.
For a media publisher: Normal user behavior involves reading a few articles, following internal links, and spending a measurable amount of time on each page. An anomaly would be a script that hits thousands of article URLs per minute, spending less than a second on each, purely to extract the text content for AI model training.
In each case, the malicious activity is defined not by a universal signature, but by its deviation from the application’s unique, established norm.
Step 3: Generating actionable findings
Detecting an anomaly is only half the battle. The power of bot management comes from its seamless integration into the Cloudflare security ecosystem you already use, turning detection into immediate, actionable findings. Customers can benefit from these behavioral detection improvements in two ways:
New Bot Detection IDs: For our Enterprise customers, we’re introducing a new set of Bot Detection IDs. Website owners and security teams can write WAF security rules to challenge, rate-limit, or block traffic based on the specific anomalies flagged by these detections. Since each detection type is tied to a unique ID, customers can see exactly what kind of behavior caused a request to be flagged as anomalous, offering a detailed, per-request view into stealthy malicious traffic. And for a wider view, customers can filter by Detection ID from their Security Analytics, to see the bigger picture of all traffic captured by that detection type.
Improving Bot Score: Another key output from these new, per-customer models will be to directly influence the Bot Score of a request. A request flagged as anomalous will have its score lowered, moving it into the “Likely Automated” (scores 2-29) or “Automated” (score 1) categories. This means that existing WAF custom rules based on Bot Score will automatically see impact and become more effective against bespoke attacks, with no changes required. This functionality update is available today for our latest account takeover detection, residential proxy detections and our recent enhancements, and will be implemented in the future for our behavioral scraping detection.
This three-step process is already in action with our behavioral detections to catch account takeover attacks. Taking bot detection ID 201326598 as an example: it (1) establishes a zone-level baseline that understands what normal traffic patterns look like for a specific website, (2) examines anomalous login failures to identify brute force and credential stuffing attacks, then (3) allows customers to mitigate these attacks by automatically influencing bot score and offering more visibility with the detection ID’s analytics.
This integration strategy creates a flywheel effect: the new intelligence from these improved detections immediately enhances the value of existing products like Super Bot Fight Mode, Bot Management, and the WAF, making the entire Cloudflare platform stronger for you.
Taking on sophisticated scrapers
The first challenge we’re tackling is sophisticated scraping. AI-driven scraping is one of the most pressing and rapidly evolving threats facing website owners today, and its adaptive nature makes it an ideal adversary for a system designed to fight an enemy that constantly changes its tactics.
The first generation of our improved behavioral detections are tuned specifically to detect scraping by analyzing signals that go beyond simple request headers. These include:
Behavioral Analysis: Looking at session traversal paths, the sequence of requests, and interaction (or lack thereof) with dynamic page elements.
Client Fingerprinting: Analyzing subtle signals from the client to identify signs of automation such as JA4 fingerprints in the context of the customer’s specific traffic baseline.
Content-Agnostic Detection: These models do not need to understand the content of a page, only the patterns of how it is being accessed. This makes them highly scalable and efficient, without actually using the unique content on a website to make judgement calls.
How do these scraping detections look, in practice? We validated our logic for detecting scraping with early adopters in a closed beta, in order to receive ground-truth feedback and tune our detections. As with any ideal detection, our goal is to capture as much malicious traffic as possible, without compromising the experience of legitimate website visitors. Looking at just a 24-hour period, our new scraping detections have caught hundreds of millions of requests, flagging 138 million scraping requests on just 5 of our early beta zones.
Naturally, we see an overlap with our existing system of bot scoring, but the numbers here show us concretely that our new method of behavioral detections have a completely new value add: 34% of the requests flagged by our new scraping detections would not have been detected by our existing bot score system, making us all the more eager to use these novel detections to inform the way we score automation.
A birthday gift for the Internet
Our mission to help build a better Internet means that when we develop powerful new defenses, we believe in democratizing access to them. Protecting the entire Internet from new and evolving threats requires raising the baseline of security for everyone.
In that spirit, we’re excited to announce that our enhanced behavioral detections will not only roll out to bot management customers, but will also benefit Cloudflare customers using our global Super Bot Fight Modesystem. For our Enterprise Bot Management customers, we automatically tune our detections based on the exact traffic for each zone. Because these advanced models are trained on your zone’s specific traffic, they detect even the most evasive attacks: from account takeovers to web scraping to other attacks executed through residential proxy networks — and we consider this only the tip of the iceberg of behavioral bot profiling.
The road ahead
Our initial focus on scraping is just the beginning of a new wave of behavioral bot detections. The infrastructure we’ve built is a flexible, powerful foundation for tackling a wide range of malicious behavior on your websites; the same principles of establishing a per-customer baseline and detecting anomalies can be applied to other critical threats that are unique to an application’s logic, such as credential stuffing, inventory hoarding, carding attacks, and API abuse.
We are moving into an era where generic defenses are no longer enough. As threats become more personal, so must the defenses against them, and paving this path of behavioral detections is our latest gift to the Internet. Our first offering of scraping behavioral detections is just around the corner: customers will be able to turn on this new detection from the Security Overview page in their dashboard.
(We’re always looking for enthusiastic humans to help us in our mission against bots! If you’re interested in helping us build a better Internet, check out our open positions.)
In 2025, Generative AI is reshaping how people and companies use the Internet. Search engines once drove traffic to content creators through links. Now, AI training crawlers — the engines behind commonly-used LLMs — are consuming vast amounts of web data, while sending far fewer users back. We covered this shift, along with related trends and Cloudflare features (like pay per crawl) in early July. Studies from Pew Research Center (1, 2) and Authoritas already point to AI overviews — Google’s new AI-generated summaries shown at the top of search results — contributing to sharp declines in news website traffic. For a news site, this means lots of bot hits, but far fewer real readers clicking through — which in turn means fewer people clicking on ads or chances to convert to subscriptions.
Cloudflare’s data shows the same pattern. Crawling by search engines and AI services surged in the first half of 2025 — up 24% year-over-year in June — before slowing to just 4% year-over-year growth in July. How is the space evolving? Which crawling purposes are most common, and how is that changing? Spoiler: training-related crawling is leading the way. In this post, we track AI and search bot crawl activity, what purposes dominate, and which platforms contribute the least referral traffic back to creators.
Key takeaways
Training crawling grows: Training now drives nearly 80% of AI bot activity, up from 72% a year ago.
Publisher referrals drop: Google referrals to news sites fell, with March 2025 down ~9% compared to January.
AI & search crawling increase: Crawling rose 32% year-over-year in April 2025, before slowing to 4% year-over-year growth in July.
AI-only crawler shifts: OpenAI’s GPTBot more than doubled in share of AI crawling traffic (4.7% to 11.7%), Anthropic’s ClaudeBot rose (6% to ~10%), while ByteDance’s Bytespider fell from 14.1% to 2.4%.
Crawl-to-refer imbalance (how many pages a bot crawls per page that a user clicks back to): Anthropic increased referrals but still leads with 38,000 crawls per visitor in July (down from 286,000:1 in January). Perplexity decreased referrals in 2025 — with more crawling but fewer referrals at 194 crawls per visitor in July.
Referral traffic from search is already shifting, as we noted above and as studies have shown. In our dataset of news-related customers (spanning the Americas, Europe, and Asia), Google’s referrals have been clearly declining since February 2025. This drop is unusual, since overall Internet traffic (and referrals as well) historically has only dipped during July and August — the summer months when the Northern Hemisphere is largely on break from school or work. The sharpest and least seasonal decline came in March. Despite being a 31-day month, March had almost the same referral volume as the shorter, 28-day February.
Looking at longer comparisons: March 2025 referral traffic from Google was 9% lower than January, the same drop seen in June. April was worse, down 15% compared with January.
This drop seems to coincide with some of Google’s changes. AI Overviews launched in the U.S. in May 2024, but in March 2025, Google upgraded AI Overviews with Gemini 2.0, introduced AI Mode in Labs, and expanded Overviews to more European countries. By May 2025, AI Mode rolled out broadly in the U.S. with Gemini 2.5, adding conversational search, Deep Search, and personalized recommendations.
The search-to-news site pipeline seems to be weakening, replaced in part by AI-driven results.
Looking at a daily perspective, we can also spot a clear U.S.-election-related peak in referrals from Google to the cohort of known news sites on November 5–6, 2024.
AI and search crawling: spring surge (+24%), summer slowdown
In June, we talked about search and AI crawler growth, and our picture of the trend is now more complete with more data. To focus only on AI and search crawlers, and to remove the bias of customer growth, we analyzed a fixed set of customers from specific weeks, a method we’ve also used in the Cloudflare Radar Year in Review.
What the data shows: crawling spiked twice: first in November 2024, then again between March and April 2025. April 2025 alone was up 32% compared with May 2024, the first full month where we have comparable data. After that surge, growth stabilized. In June 2025, crawling traffic was still 24% higher year-over-year, but by July the increase was down to just 4%. That shift highlights how quickly crawler activity can accelerate and then cool down.
As the chart below shows, crawling traffic rose sharply in March and April. It remained high but slightly lower in May, before starting to drop in June. The seasonal dip is similar to what we see in overall Internet traffic during the Northern Hemisphere’s summer months (August and September are often the quietest), though in the case of crawlers, this is likely due to reduced overall web activity rather than bots themselves taking a “break.” Historically, activity tends to rise again in November — as it did in 2024 for AI and search bot traffic — when people spend more time online for shopping and seasonal habits (a pattern we’ve seen in past years).
Googlebot is still the anchor, accounting for 39% of all AI and search crawler traffic, but the fastest growth now comes from AI-specific crawlers, though bots related to Amazon and ByteDance (Bytespider) have lost significant ground. GPTBot’s share grew from 4.7% in July 2024 to 11.7% in July 2025. ClaudeBot also increased, from 6% to nearly 10%, while Meta’s crawler jumped from 0.9% to 7.5%. By contrast, Amazonbot dropped from 10.2% to 5.9%, and ByteDance’s Bytespider dropped from 14.1% to just 2.4%.
The table below shows how market shares have shifted between July 2024 and July 2025:
Bot name
% share July 2024
% share July 2025
Δ percentage-point change
1
Googlebot
37.5
39
1.5
2
GPTBot
4.7
11.7
7
3
ClaudeBot
6
9.9
3.9
4
Bingbot
8.7
9.3
0.6
5
Meta-ExternalAgent
0.9
7.5
6.5
6
Amazonbot
10.2
5.9
-4.3
7
Googlebot-Image
4.1
3.3
-0.8
8
Yandex
5
2.9
-2.1
9
GoogleOther
4.6
2.7
-1.8
10
Bytespider
14.1
2.4
-11.6
11
Applebot
1.8
1.5
-0.3
12
ChatGPT-User
0.1
0.9
0.9
13
OAI-SearchBot
0
0.9
0.9
14
Baiduspider
0.5
0.5
0
15
Googlebot-Mobile
0.2
0.4
0.2
AI-only crawlers: OpenAI rises, ByteDance falls
Looking only at AI bot traffic (as tracked on our Radar AI page), the trend is clear. Since January 2025, GPTBot has steadily increased its crawling volume, driven mainly by training-related activity. ClaudeBot crawling accelerated in June, while Amazonbot and Bytespider activity slowed.
The chart below shows how GPTBot surged over the past 12 months, overtaking Amazonbot and Bytespider, which both fell sharply:
A comparison between July 2024 and July 2025 makes the shift even more obvious. GPTBot gained 16 percentage points, Meta’s crawler rose by more than 15, and ClaudeBot grew by 8. On the shrinking side, Amazonbot dropped 12 percentage points and Bytespider dropped over 31 percentage points.
AI-only bots
July 2024 %
July 2025 %
Δ percentage-point change
1
GPTBot
11.9
28.1
16.1
2
ClaudeBot
15
23.3
8.3
3
Meta-ExternalAgent
2.4
17.7
15.3
4
Amazonbot
26.4
14.1
-12.3
5
Bytespider
37.3
5.8
-31.5
6
Applebot
4.9
3.7
-1.2
7
ChatGPT-User
0.2
2.4
2.2
8
OAI-SearchBot
0
2.2
2.2
9
TikTokSpider
0
0.7
0.7
10
imgproxy
0
0.7
0.7
11
PerplexityBot
0
0.4
0.4
12
Google-CloudVertexBot
0
0.3
0.3
13
AI2Bot
0
0.2
0.2
14
Timpibot
0.6
0.1
-0.5
15
CCBot
0.1
0.1
0
We covered the functionality of these bots in our June blog post.
Crawling by purpose: training dominates
Training is the clear leader. (We classify purpose based on operator disclosures and industry sources, a method we explained in this AI Week blog.) Over the past 12 months, 80% of AI crawling was for training, compared with 18% for search and just 2% for user actions. In the last six months, the share for training rose further to 82%, while search dropped to 15% and user actions increased slightly to 3%.
The chart below shows how training-related crawling steadily grew over the past year, far outpacing other purposes:
The year-over-year comparison reinforces this trend. In July 2024, training accounted for 72% of AI crawling. By July 2025, it had risen to 79%. Over the same period, search fell from 26% to 17%, while user actions grew modestly from 2% to 3.2%.
Crawl-to-refer ratios shifts: tens of thousands of bot crawls per human click
The crawl-to-refer ratio measures how many pages a platform crawls compared with how often it drives users to a website. In practice, a high ratio means heavy crawling but little referral traffic. For example, for every visitor Anthropic refers back to a website, its crawlers have already visited tens of thousands of pages.
Why does this metric matter? It highlights the imbalance between how much content AI systems consume and how little traffic they return. For publishers, it can feel like giving away the raw material for free. With that in mind, here’s how different platforms compare from January to July 2025.
Anthropic remains the most crawl-heavy platform. Even after an 87% decline this year, it still crawled 38,000 pages for every referred page visit in July 2025 — the highest imbalance among major AI players. Referrals may be improving, though, after Anthropic added web search to Claude in March 2025 (initially for U.S. paid users) and expanded it globally by May to all users, including the free tier. The feature introduced direct citations with clickable URLs, creating new referral pathways.
The full dataset is below, showing January–July 2025 ratios by platform ordered by the highest ratio average:
(Note: a rising ratio means more bot crawling per human click sent back, while a falling ratio means less bot crawling per human click sent back)
Anthropic recorded the steepest decrease in bot to human traffic, down 86.7%. From 286,930 bots per human in January, to 38,065 bots per human in July, the change shows a dramatic increase in referrals. Despite the change, it remains by far the most crawl-heavy platform, with tens of thousands of pages still crawled for every referral.
Perplexity moved in the opposite direction, with bot crawling increasing +256.7% relative to human visitors; climbing from 54 bots per human in January to 195 bots per human in July. While the ratio is still far below Anthropic, the increase shows it is crawling more heavily, relative to the traffic it refers, than it did earlier.
OpenAI ratio dropped slightly, from 1,217 bots per human in January to 1,091 in July (-10%). The shift is smaller than Anthropic’s but suggests OpenAI is sending a bit more referral traffic relative to its crawling.
Microsoft stayed steady, with its ratio moving only slightly, from 38.5 bots per human in January to 40.7 in July (+6%). This consistency suggests stable behavior from Bing-linked services.
Yandex increased from 15.5 bots per human in January to 21.4 in July (+38%). The overall ratio is far smaller than Anthropic’s or Perplexity’s, but it shows Yandex is crawling more heavily relative to the traffic it sends back.
Alongside measuring crawling volumes and referral traffic (now also visible on the AI Insights page of Cloudflare Radar), it’s worth looking at whether AI operators follow good practices when deploying their bots. Cloudflare data shows that most leading AI crawlers are on our verified bots list, meaning their IP addresses match published ranges and they respect robots.txt. But adoption of newer standards like WebBotAuth — which uses cryptographic signatures in HTTP messages to confirm a request comes from a specific bot, and is especially relevant today — is still missing.
Google, Meta, and OpenAI run distinct bots for different purposes, while Anthropic lags in verification. That makes it easier for bad actors to spoof its crawler and ignore robots.txt, since without verification, it’s hard to distinguish real from fake traffic — leaving its compliance effectively unclear. (A longer list of AI bots is available here).
Conclusion and what’s next
If training-related crawling continues to dominate while referrals stay flat, creators face a paradox: feeding AI systems without gaining traffic in return. Many want their content to appear in chatbot answers, but without monetization or cooperation, the incentive to produce quality work declines.
The Web now stands at a fork in the road. Either a new balance emerges — one where the new AI era helps sustain publishers and creators — or AI turns the open web into a one-way training set, extracting value with little flowing back.
You can learn more about some of these data trends on Cloudflare Radar’s updated AI Insights page.
Search platforms historically crawled web sites with the implicit promise that, as the sites showed up in the results for relevant searches, they would send traffic on to those sites — in turn leading to ad revenue for the publisher. This model worked fairly well for several decades, with a whole industry emerging around optimizing content for optimal placement in search results. It led to higher click-through rates, more eyeballs for publishers, and, ideally, more ad revenue. However, the emergence of AI platforms over the last several years, and the incorporation of AI “overviews” into classic search platforms, has turned the model on its head. When users turn to these AI platforms with queries that used to go to search engines, they often won’t click through to the original source site once an answer is provided — and that assumes that a link to the source is provided at all! No clickthrough, no eyeballs, and no ad revenue.
To provide a perspective on the scope of this problem, Radar launchedcrawl/refer ratios on July 1, based on traffic seen across our whole customer base. These ratios effectively compare the number of crawling requests for HTML pages from the crawler associated with a given platform, to the number of HTML page requests referred by that platform (measuring human traffic). This data complements insights into AI bot & crawler traffic trends that were launched during Birthday Week 2024.
Today, we’re adding two new capabilities to the AI Insights page on Cloudflare Radar to give you more insight into this activity: industry-focused AI bot traffic data, and a new breakdown of AI bot traffic by its purpose.
Traffic by type
Since the launch of LLMs into the public consciousness in November 2022, much of the crawling traffic seen from user agents associated with AI platforms has been to collect content used to train AI models. This crawling activity can be aggressive at times, often ignoring directives found in robots.txt files. In addition to offering chatbots trained on this scraped content, AI platforms have emerged that aim to replace classic search tools, while those tools have themselves integrated AI-powered summaries as part of their results. These platforms may crawl your site to build indexes for their search engines. And some AI platforms may crawl your site in response to a specific user prompt, such as looking for flights to plan a vacation.
The new Crawl purpose selector within the AI bot & crawler traffic card allows users to select between Training, Search, User action, and Undeclared. (The latter is for crawlers where no information is available from the operator or other industry sources regarding its purpose.)
Once a purpose is selected, the HTTP traffic by bot graph updates to show traffic trends over the selected time period for the top five most active AI bots that crawl for the selected purpose.
As an example, selecting User action results in a graph like the one below, which covers the first 28 days of July 2025. OpenAI’s ChatGPT-User bot is responsible for nearly three quarters of the request traffic from this cohort of crawlers. A daily cycle is clearly evident, suggesting regular usage of ChatGPT in that fashion, with such usage gradually increasing throughout the month. If ChatGPT-User is removed from the chart, Perplexity-User also exhibits a similar pattern.
A new Crawl purpose graph has also been added to Radar, breaking out traffic trends by purpose. Training traffic, responsible for nearly 80% of the crawling from AI bots, is somewhat erratic in nature, with no clear cyclical pattern. However, such patterns are visible for the User action and Undeclared purposes, as shown in the graph below, although they account for less than 5% of AI bot traffic across this time period.
You can use your own traffic data to see how aggressively crawlers scrape your content. You can also see how frequently they refer traffic back to you. However, you may also want to understand how those measurements compare with your peer group — are you being crawled more or less frequently, and are the platforms referring more or less traffic back to your sites? The new industry set filtering available for the HTTP traffic by bot graph and the Crawl-to-refer ratio table in the AI Insights section of Radar can provide you with this perspective.
Within the AI bot & crawler traffic card on the AI Insights page, select an industry set from the drop-down list at the top right of the card. The graphs in the HTTP traffic by bot and Crawl purpose sections of the card update to reflect the selection, as does the Crawl-to-refer ratio table. (Selecting a Crawl purpose from that drop-down menu will further update the HTTP traffic by bot graph.)
It is interesting to observe how the crawling patterns change between industry sets, along with the mix of most active bots and crawl-to-refer ratios. For example, across the first week of August, with no vertical or crawl purpose selected, ClaudeBot and GPTBot account for nearly half of the observed crawling activity, with Meta-ExternalAgent the only one among the top five exhibiting activity that remotely resembles a pattern. For the default view, Anthropic had the highest crawl-to-refer ratio at nearly 50,000:1, followed by OpenAI at 887:1 and Perplexity at 118:1.
However, when the News and Publications industry set is selected, we seea much tighter distribution of traffic among the top five, ranging from ChatGPT-User’s 14.9% share of traffic to GPTBot’s 17.4% share. ChatGPT-User’s presence among the top five suggests that a significant number of users may have been asking questions about current events during that period of time. For these News and Publications sites, the crawl-to-refer ratios are lower than the default view, with Anthropic at 2,500:1, OpenAI at 152:1, and Perplexity at 32.7:1.
As a third example, we find that the mix again shifts for the Computer and Electronics industry set. While GPTBot was again the most active AI bot, Amazonbot moved up into second place; together these bots now account for over 40% of crawling traffic. ClaudeBot and Meta-ExternalAgent both had a 13.9% share of the crawling traffic, with ByteDance’s ByteSpider rounding out the top five. The crawl-to-refer ratios for this vertical are again lower than for the unfiltered view, with Anthropic down to 8,800:1, OpenAI at 401.7:1, and Perplexity at 88:1.
Within Data Explorer, you can now break down AI Bots & Crawler data by Vertical and Industry. (A vertical is a pre-defined collection of multiple related industries), and you can also filter Crawl purpose and User agent breakdowns by Vertical and Industry. For example, the graphs below illustrate the traffic trends by AI crawler for sites within the Cryptocurrency industry under the Finance vertical, as well as the traffic trends by crawl purpose for that industry/vertical pair. While these sites see crawling traffic from quite a few bots, three-quarters of that traffic during the first week of August was concentrated in just four bots, and 80% of it was for gathering information to train models.
Because the Industry sets shown on the main AI Insights page are manually curated collections of related industries, clicking through to the Data Explorer view from one of those graphs will pre-populate the Industry selector with the relevant entries. For example, clicking through from the HTTP traffic by bot graph for the Gaming & Gambling industry set results in the following Data Explorer view, which lists the component industries.
Conclusion
AI crawler traffic has become a fact of life for content owners, and the complexity of dealing with it has increased as bots are used for purposes beyond LLM training. Work is underway to allow website publishers to declare how automated systems should use their content. However, it will take some time for these proposed solutions to be standardized, and for both publishers and crawlers to adopt them. As the space evolves, we’ll continue to expand Cloudflare Radar’s insights into AI crawler activity.
Empowering content creators in the age of AI with smarter crawling controls and direct communication channels
Imagine you run a regional news site. Last month an AI bot scraped 3 years of archives in minutes — with no payment and little to no referral traffic. As a small company, you may struggle to get the AI company’s attention for a licensing deal. Do you block all crawler traffic, or do you let them in and settle for the few referrals they send?
It’s picking between two bad options.
Cloudflare wants to help break that stalemate. On July 1st of this year, we declared Content Independence Day based on a simple premise: creators deserve control of how their content is accessed and used. Today, we’re taking the next step in that journey by releasing AI Crawl Control to general availability — giving content creators and AI crawlers an important new way to communicate.
AI Crawl Control goes GA
Today, we’re rebranding our AI Audit tool as AI Crawl Control and moving it from beta to general availability. This reflects the tool’s evolution from simple monitoring to detailed insights and control over how AI systems can access your content.
The market response has been overwhelming: content creators across industries needed real agency, not just visibility. AI Crawl Control delivers that control.
Using HTTP 402 to help publishers license content to AI crawlers
Many content creators have faced a binary choice: either they block all AI crawlers and miss potential licensing opportunities and referral traffic; or allow them through without any compensation. Many content creators had no practical way to say “we’re open for business, but let’s talk terms first.”
Our customers are telling us:
We want to license our content, but crawlers don’t know how to reach us.
Blanket blocking feels like we’re closing doors on potential revenue and referral traffic.
We need a way to communicate our terms before crawling begins.
To address these needs, we are making it easier than ever to send customizable402 HTTP status codes.
Our private beta launch of Pay Per Crawl put the HTTP 402 (“Payment Required”) response codes to use, working in tandem with Web Bot Auth to enable direct payments between agents and content creators. Today, we’re making customizable 402 response codes available to every paid Cloudflare customer — not just pay per crawl users.
Here’s how it works: in AI Crawl Control, paying Cloudflare customers will be able to select individual bots to block with a configurable message parameter and send 402 payment required responses. Think: “To access this content, email [email protected] or call 1-800-LICENSE” or “Premium content available via API at api.yoursite.com/pricing.”
On an average day, Cloudflare customers are already sending over one billion 402 response codes. This shows a deep desire to move beyond blocking to open communication channels and new monetization models. With the 402 HTTP status code, content creators can tell crawlers exactly how to properly license their content, creating a direct path from crawling to a commercial agreement. We are excited to make this easier than ever in the AI Crawl Control dashboard.
How to customize your 402 status code with AI Crawl Control:
For Paid Plan Users:
When you block individual crawlers from the AI Crawl Control dashboard, you can now choose to send 402 Payment Required status codes and customize your message. For example: To access this content, email [email protected] or call 1-800-LICENSE.
The response will look like this:
The message can be configured from Settings in the AI Crawl Control Dashboard:
Beyond just blocking AI bots
This is just the beginning. We’re planning to add additional parameters that will let crawlers understand the content’s value, freshness, and licensing terms directly in the 402 response. Imagine crawlers receiving structured data about content quality and update frequency, for example, in addition to contact information.
Meanwhile, pay per crawl continues advancing through beta, giving content creators the infrastructure to automatically monetize crawler access with transparent, usage-based pricing.
What excites us most is the market shift we’re seeing. We’re moving to a world where content creators have clear monetization paths to become active participants in the development of rich AI experiences.
The 402 response is a bridge between two industries that want to work together: content creators whose work fuels AI development, and AI companies who need high-quality data. Cloudflare’s AI Crawl Control creates the infrastructure for these partnerships to flourish.
On the surface, the goal of handling bot traffic is clear: keep malicious bots away, while letting through the helpful ones. Some bots are evidently malicious — such as mass price scrapers or those testing stolen credit cards. Others are helpful, like the bots that index your website. Cloudflare has segmented this second category of helpful bot traffic through our verified bots program, vetting and validating bots that are transparent about who they are and what they do.
Today, the rise of agents has transformed how we interact with the Internet, often blurring the distinctions between benign and malicious bot actors. Bots are no longer directed only by the bot owners, but also by individual end users to act on their behalf. These bots directed by end users are often working in ways that website owners want to allow, such as planning a trip, ordering food, or making a purchase.
Our customers have asked us for easier, more granular ways to ensure specific bots, crawlers, and agents can reach their websites, while continuing to block bad actors. That’s why we’re excited to introduce signed agents, an extension of our verified bots program that gives a new bot classification in our security rules and in Radar. Cloudflare has long recognized agents — but we’re now endowing them with their own classification to make it even easier for our customers to set the traffic lanes they want for their website.
But the bot landscape is constantly evolving. Let’s unpack a common type of verified AI bot — an AI crawler such as GPTBot. Even though the bot performs an array of tasks, the bot’s ultimate purpose is a singular, repetitive task on behalf of the operator of that bot: fetch and index information. Its intelligence is applied to performing that singular job on behalf of that bot owner.
Agents, though, are different. Think about an AI agent tasked by a user to “Book the best deal for a round-trip flight to New York City next month.” These agents sometimes use remote browsing products like Cloudflare’s Browser Rendering and similar products from companies like Browserbase and Anchor Browser. And here is the key distinction: this particular type of bot isn’t operating on behalf of a single company, like OpenAI in the prior example, but rather the end users themselves.
Introducing signed agents
In May, we announced Web Bot Auth, a new method of using cryptography to verify bot and agent traffic. HTTP message signatures allow bots to authenticate themselves and allow customer origins to identify them. This is one of the authentication methods we use today for our verified bots program.
What, exactly, is a signed agent? First, they are agents that are generally directed by an end user instead of a single company or entity. Second, the infrastructure or remote browsing platform the agents use is signing their HTTP requests via Web Both Auth, with Cloudflare validating these message signatures. And last, they comply with our signed agent policy.
The signed agents classification improves on our existing frameworks in a couple of ways:
Increased precision and visibility: we’ve updated the Cloudflare bots and agents directory to include signed agents in addition to verified bots. This allows us to verify the cryptographic signatures of a much wider set of automated traffic, and our customers to granularly apply their security preferences more easily. Bot operators can now submit signed agent applications from the Cloudflare dashboard, allowing bot owners to specify to us how they think we should segment their automated traffic.
Easier controls from security rules: similar to how they can take action on verified bots as a group, our Enterprise customers will be able to take action on signed agents as a group when configuring their security rules. This new field will be available in the Cloudflare dashboard under security rules soon.
To apply to have an agent added to Cloudflare’s directory of bots and agents, customers should complete the Bot Submission Form in the Cloudflare dashboard. Here, they can specify whether the submission should be considered for the signed agents list or the verified bots list. All signed agents will be recognized by their cryptographic signatures through Web Bot Auth validation.
The Bot Submission Form, available in the Cloudflare dashboard for bot owners to submit both verified bot and signed agent applications.
We want to be clear: our verified bots program isn’t going anywhere. In fact, well-behaved and transparent applications that make use of signed agents can further qualify to be a verified bot, if their specific service adheres to our policy. For instance,Cloudflare Radar’s URL Scanner, which relies on Browser Rendering as a service to scan URLs, is a verified bot. While Browser Rendering itself does not qualify to be a verified bot, URL Scanner does, since the bot owner (in this case, Cloudflare Radar) directs the traffic sent by the bot and always identifies itself with a unique Web Bot Auth signature — distinct from Browser Rendering’s signature.
From an agent’s perspective…
Since the launch of Web Bot Auth, our own Browser Rendering product has been sending signed Web Bot Auth HTTP headers, and is always given a bot score of 1 for our Bot Management customers. As of today, Browser Rendering will now show up in this new signed agent category.
We’re also excited to announce the first cohort of agents that we’re partnering with and will be classifying as signed agents: ChatGPT agent, Goose from Block, Browserbase, and Anchor Browser. They are perfect examples of this new classification because their remote browsers are used by their end customers, not necessarily the companies themselves. We’re thrilled to partner with these teams to take this critical step for the AI ecosystem:
“When we built Goose as an open source tool, we designed it to run locally with an extensible architecture that lets developers automate complex workflows. As Goose has evolved to interact with external services and third-party sites on users’ behalf, Web Bot Auth enables those sites to trust Goose while preserving what makes it unique. This authentication breakthrough unlocks entirely new possibilities for autonomous agents.” – Douwe Osinga, Staff Software Engineer, Block
“At Browserbase, we provide web browsing capabilities for some of the largest AI applications. We’re excited to partner with Cloudflare to support the adoption of Web Bot Auth, a critical layer of identity for agents. For AI to thrive, agents need reliable, responsible web access.“ – Paul Klein, CEO, Browserbase
“Anchor Browser has partnered with Cloudflare to let developers ship verified browser agents. This way trustworthy bots get reliable access while sites stay protected.” – Idan Raman, CEO, Anchor Browser
Updated visibility on Radar
We want everyone to be in the know about our bot classifications. Cloudflare began publishing verified bots on our Radar page back in 2022, meaning anyone on the Internet — Cloudflare customer or not — can see all of our verified bots on Radar. We dynamically update the list of bots, but show more than just a list: we announced on Content Independence Day that every verified bot would get its own page in our public-facing directory on Radar, which includes the traffic patterns that we see for each bot.
Our directory has been updated to include both signed agents and verified bots — we share exactly how Cloudflare classifies the bots that it recognizes, plus we surface all of the traffic that Cloudflare observes from these many recognized agents and bots. Through this updated directory, we’re not only giving better visibility to our customers, but also striving to set a higher standard for transparency of bot traffic on the Internet.
Cloudflare Radar’s Bots Directory, which lists verified bots and signed agents. This view is filtered to view only agent entries.
Cloudflare Radar’s signed agent page for ChatGPT agent, which includes its traffic patterns for the last 7 days, from August 21, 2025 to August 27, 2025.
What’s now, what’s next
As of today, the Cloudflare bot directory supports both bots and agents in a more clear-cut way, and customers or agent creators can submit agents to be signed and recognized through their account dashboard. In addition, anyone can see our signed agents and their traffic patterns on Radar. Soon, customers will be able to take action on signed agents as a group within their firewall rules, the same way you can take action on our verified bots.
Agents are changing the way that humans interact with the Internet. Websites need to know what tools are interacting with them, and for the builders of those tools to be able to easily scale. Message signatures help achieve both of these goals, but this is only step one. Cloudflare will continue to make it easier for agents and websites to interact (or not!) at scale, in a seamless way.
Today, we are announcing Cloudflare’s Browser Developer Program, a collaborative initiative to strengthen partnership between Cloudflare and browser development teams.
At Cloudflare, we aim to help build a better Internet. One way we achieve this is by providing website owners with the tools to detect and block unwanted traffic from bots through Cloudflare Challenges or Turnstile. As both bots and our detection systems become more sophisticated, the security checks required to validate human traffic become more complicated. While we aim to strike the right balance, we recognize these security measures can sometimes cause issues for legitimate browsers and their users.
Building a better web together
A core objective of the program is to provide a space for intentional collaboration where we can work directly with browser developers to ensure that both accessibility and security can co-exist. We aim to support the evolving browser landscape, while upholding our responsibility to our customers to deliver the best security products. This program provides a dedicated channel for browser teams to share feedback, report issues, and help ensure that Cloudflare’s Challenges and Turnstile work seamlessly with all browsers.
What the program includes
Browser developers in the program will benefit from:
A two-way communication channel to Cloudflare’s team dedicated to addressing browser-specific concerns, feedback, and issues.
Best practices for building and testing against Cloudflare Challenges and Turnstile.
A private community forum for updates, questions, and discussion between browser developers and Cloudflare engineers.
Early visibility into updates or changes to that may impact how your browser handles Cloudflare Challenges.
(If applicable) Testing integration where we will incorporate your browser into our testing pipeline and monitor its performance with our releases.
This program is designed as a partnership where Cloudflare will, with our best effort, ensure our security products work properly with all browsers, while giving browser developers a voice in how these systems evolve. As an output of this program, we expect to publish clear browser requirements to run Cloudflare Challenges while striking the balance between openness and security.
For end users browsing the web, we continue to support a wide range of browsers. We will continue to update this list based on the insights and collaborations from the Browser Developer Program. We are also committed to ensuring our Challenge interstitial pages and Turnstile provide clear, actionable UI/UX for any error or failed states, making it easier for you to understand and resolve issues you may encounter.
How to apply
If you are working on a browser and want to ensure your users have a seamless experience with Cloudflare-protected websites, we encourage you to apply here.
We’ll ask for basic information about your project and ask you to sign our Browser Developer Program Agreement. In addition, we expect participants to adhere to our Community Code of Conduct and commit to constructive engagement.
Once you’re accepted, you’ll be invited to a private space in the Cloudflare Community where you can engage directly with our team.
Why is this important?
Cloudflare Challenges, a security mechanism to verify whether a visitor is a human or a bot, serve a wide variety of browsers in the world today. Chrome leads with 68.0%, Safari at 8.7%, Firefox at 6.3%, Edge at 4.8%, and Opera at 6.2%. However, the very long tail of browsers that collectively make up the remaining traffic, each representing less than 1% individually but together painting a picture of an incredibly diverse web ecosystem.
Browser traffic distribution, with 100+ browsers comprising the ‘Other’ category
This diversity spans a wide range of environments, each with unique constraints and capabilities:
Emerging and experimental browsers pushing the boundaries of web technology
Privacy-focused browsers such as DuckDuckGo that prioritize user data protection
Embedded browsers inside social media apps like Facebook, Instagram, and TikTok
WebViews used by mobile applications
Gaming and VR browsers such as Oculus for headsets and gaming consoles
Smart device browsers built into classroom displays and home appliances
Supporting this level of diversity poses real engineering challenges. Many of these browsers deviate from standard assumptions. Some lack full support for modern Web APIs, others operate under more stringent data privacy policies, and some are optimized for environments where our script to verify visitors may be hindered or blocked from running properly. These browsers are not bad or malicious. But their behavior may fall outside the typical patterns observed in mainstream browsers, which can lead to problematic or failed Challenge flows which we would like to avoid.
From an engineering perspective, our job is to strike a difficult balance. If our logic is too rigid that it expects only the behaviors of the majority, we risk excluding legitimate users on less conventional platforms. But if we relax our standards too much, we increase the attack surface for abuse. We cannot overfit to the top 5 browsers, nor can we afford to treat all clients as equal in capability or trustworthiness.
The Browser Developer Program is one way to close this gap. By working directly with browser teams, especially those building for niche or emerging environments, we can better understand the constraints they operate under and collaborate to make each of our systems more compatible and resilient.
Join us!
This program is free to join, and is open to any browser developer, no matter the size or the lifecycle stage. Our goal is to listen, learn, and collaborate with browser developers to create a better experience for everyone.
We believe this program will ultimately benefit end users the most. By joining this program, you will help us build solutions that prioritize both the security needs of businesses as well as the diverse ways people access the Internet.
We are observing stealth crawling behavior from Perplexity, an AI-powered answer engine. Although Perplexity initially crawls from their declared user agent, when they are presented with a network block, they appear to obscure their crawling identity in an attempt to circumvent the website’s preferences. We see continued evidence that Perplexity is repeatedly modifying their user agent and changing their source ASNs to hide their crawling activity, as well as ignoring — or sometimes failing to even fetch — robots.txtfiles.
The Internet as we have known it for the past three decades is rapidly changing, but one thing remains constant: it is built on trust. There are clear preferences that crawlers should be transparent, serve a clear purpose, perform a specific activity, and, most importantly, follow website directives and preferences. Based on Perplexity’s observed behavior, which is incompatible with those preferences, we have de-listed them as a verified bot and added heuristics to our managed rules that block this stealth crawling.
How we tested
We received complaints from customers who had both disallowed Perplexity crawling activity in their robots.txt files and also created WAF rules to specifically block both of Perplexity’s declared crawlers: PerplexityBot and Perplexity-User. These customers told us that Perplexity was still able to access their content even when they saw its bots successfully blocked. We confirmed that Perplexity’s crawlers were in fact being blocked on the specific pages in question, and then performed several targeted tests to confirm what exact behavior we could observe.
We created multiple brand-new domains, similar to testexample.com and secretexample.com. These domains were newly purchased and had not yet been indexed by any search engine nor made publicly accessible in any discoverable way. We implemented a robots.txt file with directives to stop any respectful bots from accessing any part of a website:
We conducted an experiment by querying Perplexity AI with questions about these domains, and discovered Perplexity was still providing detailed information regarding the exact content hosted on each of these restricted domains. This response was unexpected, as we had taken all necessary precautions to prevent this data from being retrievable by their crawlers.
Obfuscating behavior observed
Bypassing Robots.txt and undisclosed IPs/User Agents
Our multiple test domains explicitly prohibited all automated access by specifying in robots.txt and had specific WAF rules that blocked crawling from Perplexity’s public crawlers. We observed that Perplexity uses not only their declared user-agent, but also a generic browser intended to impersonate Google Chrome on macOS when their declared crawler was blocked.
Declared
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)
20-25m daily requests
Stealth
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/124.0.0.0 Safari/537.36
3-6m daily requests
Both their declared and undeclared crawlers were attempting to access the content for scraping contrary to the web crawling norms as outlined in RFC 9309.
This undeclared crawler utilized multiple IPs not listed in Perplexity’s official IP range, and would rotate through these IPs in response to the restrictive robots.txt policy and block from Cloudflare. In addition to rotating IPs, we observed requests coming from different ASNs in attempts to further evade website blocks. This activity was observed across tens of thousands of domains and millions of requests per day. We were able to fingerprint this crawler using a combination of machine learning and network signals.
An example:
Of note: when the stealth crawler was successfully blocked, we observed that Perplexity uses other data sources — including other websites — to try to create an answer. However, these answers were less specific and lacked details from the original content, reflecting the fact that the block had been successful.
How well-meaning bot operators respect website preferences
In contrast to the behavior described above, the Internet has expressed clear preferences on how good crawlers should behave. All well-intentioned crawlers acting in good faith should:
Be transparent. Identify themselves honestly, using a unique user-agent, a declared list of IP ranges or Web Bot Auth integration, and provide contact information if something goes wrong.
Be well-behaved netizens. Don’t flood sites with excessive traffic, scrape sensitive data, or use stealth tactics to try and dodge detection.
Serve a clear purpose. Whether it’s powering a voice assistant, checking product prices, or making a website more accessible, every bot has a reason to be there. The purpose should be clearly and precisely defined and easy for site owners to look up publicly.
Separate bots for separate activities. Perform each activity from a unique bot. This makes it easy for site owners to decide which activities they want to allow. Don’t force site owners to make an all-or-nothing decision.
Follow the rules. That means checking for and respecting website signals like robots.txt, staying within rate limits, and never bypassing security protections.
OpenAI is an example of a leading AI company that follows these best practices. They clearly outline their crawlers and give detailed explanations for each crawler’s purpose. They respect robots.txt and do not try to evade either a robots.txt directive or a network level block. And ChatGPT Agent is signing http requests using the newly proposed open standard Web Bot Auth.
When we ran the same test as outlined above with ChatGPT, we found that ChatGPT-User fetched the robots file and stopped crawling when it was disallowed. We did not observe follow-up crawls from any other user agents or third party bots. When we removed the disallow directive from the robots entry, but presented ChatGPT with a block page, they again stopped crawling, and we saw no additional crawl attempts from other user agents. Both of these demonstrate the appropriate response to website owner preferences.
How can you protect yourself?
All the undeclared crawling activity that we observed from Perplexity’s hidden User Agent was scored by our bot management system as a bot and was unable to pass managed challenges. Any bot management customer who has an existing block rule in place is already protected. Customers who don’t want to block traffic can set up rules to challenge requests, giving real humans an opportunity to proceed. Customers with existing challenge rules are already protected. Lastly, we added signature matches for the stealth crawler into our managed rule that blocks AI crawling activity. This rule is available to all customers, including our free customers.
What’s next?
We announced Content Independence Day almost one month ago, giving content creators and publishers more control over how their content is accessed. Today, over two and a half million websites have chosen to completely disallow AI training through our managed robots.txt feature or our managed rule blocking AI Crawlers. Every Cloudflare customer is now able to selectively decide which declared AI crawlers are able to access their content in accordance with their business objectives.
We expected a change in bot and crawler behavior based on these new features, and we expect that the techniques bot operators use to evade detection will continue to evolve. Once this post is live the behavior we saw will almost certainly change, and the methods we use to stop them will keep evolving as well.
Cloudflare is actively working with technical and policy experts around the world, like the IETF efforts to standardize extensions to robots.txt, to establish clear and measurable principles that well-meaning bot operators should abide by. We think this is an important next step in this quickly evolving space.
As a site owner, how do you know which bots to allow on your site, and which you’d like to block? Existing identification methods rely on a combination of IP address range (which may be shared by other services, or change over time) and user-agent header (easily spoofable). These have limitations and deficiencies. In our last blog post, we proposed using HTTP Message Signatures: a way for developers of bots, agents, and crawlers to clearly identify themselves by cryptographically signing requests originating from their service.
Since we published the blog post on Message Signatures and the IETF draft for Web Bot Auth in May 2025, we’ve seen significant interest around implementing and deploying Message Signatures at scale. It’s clear that well-intentioned bot owners want a clear way to identify their bots to site owners, and site owners want a clear way to identify and manage bot traffic. Both parties seem to agree that deploying cryptography for the purposes of authentication is the right solution.
Today, we’re announcing that we’re integrating HTTP Message Signatures directly into our Verified Bots Program. This announcement has two main parts: (1) for bots, crawlers, and agents, we’re simplifying enrollment into the Verified Bots program for those who sign requests using Message Signatures, and (2) we’re encouraging all bot operators moving forward to use Message Signatures over existing verification mechanisms. Because Verified Bots are considered authenticated, they do not face challenges from our Bot Management to identify as bots, given they’re already identified as such.
For site owners, no additional action is required – Cloudflare will automatically validate signatures on our edge, and if that validation is a success, that traffic will be marked as verified so that site owners can use the verified bot fields to create Bot Management and WAF rules based on it.
This isn’t just about simplifying things for bot operators — it’s about giving website owners unparalleled accuracy in identifying trusted bot traffic, cutting down on the overhead for cryptographic verification, and fundamentally transforming how we manage authentication across the Cloudflare network.
Become a Verified Bot with Message Signatures
Cloudflare’s existing Verified Bots program is for bots that are transparent about who they are and what they do, like indexing sites for search or scanning for security vulnerabilities. You can see a list of these verified bots in Cloudflare Radar:
A preview of the Verified Bots page on Cloudflare Radar.
In the past, in order to apply to be a verified bot, we used to ask for IP address ranges or reverse DNS names so that we could verify your identity. This required some manual steps like checking that the IP address range is valid and is associated with the appropriate ASN.
With the integration of Message Signatures, we’re aiming to streamline applications into our Verified Bot program. Bots applying with well-formed Message Signatures will be prioritized, and approved more quickly!
At a high level, signing your requests with web bot auth consists of the following steps:
Generate a valid signing key. See Signing Key section for step-by-step instructions.
Host a JSON web key set containing your public key under /.well-known/http-message-signature-directory of your website.
Sign responses for that URL using a Web Bot Auth library, one signature for each key contained in it, to prove you own it. See the Hosting section for step-by-step instructions.
Register that URL with us, using our Verified Bots form. This can be done directly in your Cloudflare account. See our documentation.
Sign requests using a Web Bot Auth library.
As an example, Cloudflare Radar’s URL Scanner lets you scan any URL and get a publicly shareable report with security, performance, technology, and network information. Here’s an example of what a well-formed signature looks like for requests coming from URL Scanner:
GET /path/to/resource HTTP/1.1
Host: www.example.com
User-Agent: Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/119.0.0.0 Safari/537.36
Signature-Agent: "https://web-bot-auth-directory.radar-cfdata-org.workers.dev"
Signature-Input: sig=("@authority" "signature-agent");\
             	 created=1700000000;\
             	 expires=1700011111;\
             	 keyid="poqkLGiymh_W0uP6PZFw-dvez3QJT5SolqXBCW38r0U";\
             	 tag="web-bot-auth"
Signature:sig=jdq0SqOwHdyHr9+r5jw3iYZH6aNGKijYp/EstF4RQTQdi5N5YYKrD+mCT1HA1nZDsi6nJKuHxUi/5Syp3rLWBA==:
Since we’ve already registered URLScanner as a Verified Bot, Cloudflare will now automatically verify that the signature in the Signature header matches the request — more on that later.
Register your bot
Access the Verified Bots submission form on your account. If that link does not immediately take you there, go to your Cloudflare account → Account Home → the three dots next to your account name → Configurations → Verified Bots.
For the verification method, select “Request Signature”, then enter the URL of your key directory in Validation Instructions. Specifying the User-Agent values is optional if you’re submitting a Request Signature bot.
Once your application has gone through our (now shortened) review process, you don’t need to take any further action.
Message Signature verification for origins
Starting today, Cloudflare is ramping up verification of cryptographic signatures provided by automated crawlers and bots. This is currently available for all Free and Pro plans, and as we continue to test and validate at scale, will be released to all Business and Enterprise plans. This means that as time passes, the number of unauthenticated web crawlers should diminish, ensuring most bot traffic is authenticated before it reaches your website’s servers, helping to prevent spoofing attacks.
At a high level, signature verification works like this:
A bot or agent sends a request to a website behind Cloudflare.
Cloudflare’s Message Signature verification service checks for the Signature, Signature-Input, and Signature-Agent headers.
It checks that the incoming request presents a keyid parameter in your Signature-Input that points to a key we already know.
It looks at the expires parameter in the incoming bot request. If the current time is after expiration, verification fails. This guards against replay attacks, preventing malicious agents from trying to pass as a bot by retrying messages they captured in the past.
It checks that you’ve specified a tag parameter indicating web-bot-auth, to indicate your intent that the message be handled using web bot authentication specifically
It looks at all the components chosen in your Signature-Input header, and constructs a signature base from it.
If all pre-flight checks pass, Cloudflare attempts to verify the signature base against the value in Signature field using an ed25519 verification algorithm and the key supplied in keyid.
Verified Bots and other systems at Cloudflare use a successful verification as proof of your identity, and apply rules corresponding to that identity.
If any of the above steps fail, Cloudflare falls back to existing bot identification and mitigation mechanisms. As the system matures, we would strengthen these requirements, and limit the possibilities of a soft downgrade.
As a site owner, you can segment your Verified Bot traffic by its type and purpose by adding the Verified Bot Categories field cf.verified_bot_category as a filter criterion in WAF Custom rules, Advanced Rate Limiting, and Late Transform rules. For instance, to allow the Bibliothèque nationale de France and the Library of Congress, and institutions dedicated to academic research, you can add a rule that allows bots in the Academic Research category.
Where we’re going next
HTTP Message Signatures is a primitive that is useful beyond Cloudflare – the IETF standardized it as part of RFC 9421.
As discussed in our previous blog post, Cloudflare believes that making Message Signatures a core component of bot authentication on the web should follow the same path. The specifications for the protocol are being built in the open, and they have already evolved following feedback.
Moreover, due to widespread interest, the IETF is considering forming a working group around Web Bot Auth. Should you be a crawler, an origin, or even a CDN, we invite you to provide feedback to ensure the solution gets stronger, and suits your needs.
A better, more trusted Internet
For bot, agent, and crawler operators that act transparently and provide vital services for the Internet, we’re providing a faster and more automated path to being recognized as a Verified Bot, reducing manual processes. We trust that this approach improves bot authentication from what were formerly brittle and unreliable authentication methods, to a secure and reliable alternative. It should reduce the overall volume of friction and hurdles genuinely useful bots face.
For site owners, Message Signatures provides better assurance that the bot traffic is legitimate — automatically recognized and allowed, minimizing disruption to essential services (e.g., search engine indexing, monitoring). In line with our commitments to making TLS/SSL and Post-Quantum certificates available for everyone, we’ll always offer the cryptographic verification of Message Signatures for all sites because we believe in a safer and more efficient Internet by fostering a trusted environment for both human and automated traffic.
If you have a feature request, feedback, or are interested in partnering with us, please reach out.
Web crawlers are not new. The World Wide Web Wanderer debuted in 1993, though the first web search engines to truly use crawlers and indexers were JumpStation and WebCrawler. Crawlers are part of one of the backbones of the Internet’s success: search. Their main purpose has been to index the content of websites across the Internet so that those websites can appear in search engine results and direct users appropriately. In this blog post, we’re analyzing recent trends in web crawling, which now has a crucial and complex new role with the rise of AI.
Not all crawlers are the same. Bots, automated scripts that perform tasks across the Internet, come in many forms: those considered non-threatening or “good” (such as API clients, search indexing bots like Googlebot, or health checkers) and those considered malicious or “bad” (like those used for credential stuffing, spam, or scraping content without permission). In fact, around 30% of global web traffic today, according to Cloudflare Radar data, comes from bots, and even exceeds human Internet traffic in some locations.
A new category, AI crawlers, has emerged in recent years. These bots collect data from across the web to train AI models, improving tools and experiences, but also raising issues around content rights, unauthorized use, and infrastructure overload. We aimed to confirm the growth of both search and AI crawlers, examine specific AI crawlers, and understand broader crawler usage.
This is increasingly relevant with the rapid adoption of AI, growing content rights concerns, and data privacy discussions. Some sites and creators are looking to limit or block AI crawlers using tools like robots.txt or firewall rules. Others, like Dutch indie maker and entrepreneur Pieter Levels, have embraced them: “I’m 100% fine with AI crawlers… very important to rank in LLMs [large language models]”.
It’s important to note that crawlers serve different purposes. For example, the facebookexternalhit bot is not included in this analysis, as it is used by Facebook to fetch page content when generating previews for shared links. However, within this post, we are only focusing on AI and search crawlers that are indexing or scraping website content.
AI-only crawlers perspective
Let’s start with an AI-only crawler perspective that we currently have on Cloudflare Radar, focused only on crawlers advertised as AI-related. To identify them, we’re using here a list derived from an open-source project that helps website owners manage and control access to AI crawlers — especially those used to train large language models (LLMs). It also provides guidance on what to include in robots.txtfiles (more on that below). The data shown below is based on matching those crawler names with user-agent strings in HTTP requests. (Further details, including one exception, about this method can be found at the end of the blog post.)
The AI crawler landscape saw a significant shift between May 2024 and May 2025, with GPTBot (from OpenAI) emerging as the dominant force, surging from 5% to 30% share, and Meta-ExternalAgent (from Meta) making a strong new entry at 19%. This growth came at the expense of former leader Bytespider, which plummeted from 42% to 7%, as well as other AI crawlers like ClaudeBot and Amazonbot, which also saw declines. Our data clearly indicates a reordering of top AI crawlers, highlighting the increasing prominence of OpenAI and Meta in this category.
May 2024
May 2025
Rank
Bot Name
Share (May 2024)
Rank
Bot Name
Share (May 2025)
1
Bytespider
42%
1
GPTBot
30%
2
ClaudeBot
27%
2
ClaudeBot
21%
3
Amazonbot
21%
3
Meta-ExternalAgent
19%
4
GPTBot
5%
4
Amazonbot
11%
5
Applebot
4.1%
5
Bytespider
7.2%
Rank
Bot Name
Share (May 2024)
Rank
Bot Name
Share (May 2025)
1
Bytespider
42%
1
GPTBot
30%
2
ClaudeBot
27%
2
ClaudeBot
21%
3
Amazonbot
21%
3
Meta-ExternalAgent
19%
4
GPTBot
5%
4
Amazonbot
11%
5
Applebot
4.1%
5
Bytespider
7.2%
For additional context, the list below includes further information about the bots with higher crawling shares seen above. This information comes from the same open-source list mentioned above and from publications by companies like OpenAI, which explain how their crawlers are used.
GPTBot – OpenAI’s crawler used to improve and train large language models like ChatGPT.
ClaudeBot – Anthropic’s crawler for training and updating the Claude AI assistant.
Meta-ExternalAgent – Meta’s bot likely used for collecting data to train or fine-tune LLMs.
Amazonbot – Amazon’s crawler that gathers data for its search and AI applications.
Bytespider – ByteDance’s AI data collector, often linked to training models like Ernie or TikTok-related AI.
Applebot – Apple’s web crawler primarily for Siri and Spotlight search, possibly used in AI development.
OAI-SearchBot – OpenAI’s search-focused crawler, likely used for retrieving real-time web info for models.
ChatGPT-User – Represents API-based or browser usage of ChatGPT in connection with user interactions.
PerplexityBot – Crawler from Perplexity.ai, which powers their AI answer engine using real-time web data.
Webmasters can inform crawler operators of whether they want these bots and crawlers to access their content by setting out rules in a file called robots.txt, which tells crawlers what pages they should or shouldn’t access. As we’ve seen recently, crawlers honoring your robots.txt policies is voluntary, but Cloudflare announced tools like AI Audit to help content creators to enforce it.
Now, as we’ve seen, the landscape of web crawling is evolving rapidly, driven by the merging roles of search engines and AI. AI is now deeply integrated into search, seen in Google’s AI Overviews and AI Mode, but also in social media platforms, like Meta AI on Instagram. So, let’s broaden our analysis to include these wider AI-driven crawling activities.
General AI and search crawling growth: +18%
A broader view reveals the growth of crawling traffic from both search and AI crawlers over the first few months of 2025. To remove customer growth bias, we’ll analyze trends using a fixed set of customers from specific weeks (a method we’ve used in our Cloudflare Radar Year in Review): the first week of May 2024, a week in November 2024, and the first week of April 2025.
Using that method, we found that AI and search crawler traffic grew by 18% from May 2024 to May 2025 (comparing full-month periods). The increase was even higher, at 48%, when including new Cloudflare customers added during that time. Peak AI and search crawling traffic occurred in April 2025, with a 32% increase compared to May 2024. This confirms that crawling traffic has clearly risen over the past year, but also that growth is not always constant. Google remains the dominant player, and its share is growing too, as we’ll see in the next section.
As the next chart shows, crawling traffic increased sharply in March and April 2025 and remained high, though slightly lower, in May.
The patterns on the above crawling chart also seem to reflect broader seasonal patterns and general human Internet traffic patterns. In 2024, traffic dropped during the summer in the Northern Hemisphere, with August and September being the least active months. And like overall Internet traffic, it then rose in November, when people are typically more online due to shopping and seasonal habits, as we’ve seen in past analyses.
Googlebot crawling grew 96% in one year
Googlebot, which indexes content for Google Search, was clearly the top crawler throughout the period and showed strong growth, up 96% from May 2024 to May 2025, reflecting increased crawling by Google. Crawling traffic peaked in April 2025, reaching 145% higher than in May 2024. It’s also important to mention that Google made changes to its search and launched AI Overviews in its search engine during this time — first in the US in May 2024, then in more countries later.
Two trends stand out when looking at daily data for Google-related crawlers, as shown in the graph below. First, Googlebot and the more recent GoogleOther (a web crawler from 2023 for “research and development”) account for most of Google’s crawling activity. Second, there were two visible drops in crawling traffic: one on December 14, 2024 (around a Google Search update), and another from May 20 to May 28, 2025. That May 20 drop occurred around the same time as the rollout of AI Mode on Google Search in the US, although the timing may be coincidental.
Breakdown of top 20 AI and search web crawlers
Ranking crawlers by their share of total requests gives a clearer picture of which bots are gaining or losing ground, especially among those focused on search and AI. The table below shows a clear trend: some AI bots have grown rapidly since last year (with growth beginning even earlier), while many traditional search crawlers have remained flat or lost share (as in the case of Bing and its Bingbot crawler). The main exception is Googlebot.
The next table shows the percentage share of each crawler out of all crawling traffic generated by this specific cohort of over 30 AI & search crawlers observed by Cloudflare in May 2024 and May 2025. The table below also includes the change in percentage points and the growth or decline in raw request volume. Crawlers are ranked by their share in May 2025. Key crawler shifts include GPTBot rising sharply (+305%), while Bytespider dropped dramatically (-85%).
Rank
Bot name
Share
May 2024
Share
May 2025
Δ percentage-point change
Raw requests growth (May 2024 to May 2025)
1
Googlebot
30%
50%
+20 pp
96%
2
Bingbot
10%
8.7%
-1.3 pp
2%
3
GPTBot
2.2%
7.7%
+5.5 pp
305%
4
ClaudeBot
11.7%
5.4%
-6.3 pp
-46%
5
GoogleOther
4.4%
4.3%
-0.1 pp
14%
6
Amazonbot
7.6%
4.2%
-3.4 pp
-35%
7
Googlebot-Image
4.5%
3.3%
-1.2 pp
-13%
8
Bytespider
22.8%
2.9%
-19.8 pp
-85%
9
Yandex
2.8%
2.2%
-0.7 pp
-10%
10
ChatGPT-User
0.1%
1.3%
+1.2 pp
2,825%
11
Applebot
1.9%
1.2%
-0.7 pp
-26%
12
Timpibot
0.3%
0.6%
+0.3 pp
133%
13
Baiduspider
0.5%
0.4%
-0.1 pp
7%
14
PerplexityBot
<0.01%
0.2%
+0.2 pp
157,490%
15
DuckDuckBot
0.2%
0.1%
-0.1 pp
-16%
16
SeznamBot
0.1%
0.1%
2%
17
Yeti
0.1%
0.1%
47%
18
coccocbot
0.1%
0.1%
-3%
19
Sogou
0.1%
0.1%
-22%
20
Yahoo! Slurp
0.1%
0.0%
-0.1 pp
-8%
Rank
Bot name
Share May 2024
Share May 2025
Δ percentage-point change
Raw requests growth (May 2024 to May 2025)
1
Googlebot
30%
50%
+20 pp
96%
2
Bingbot
10%
8.7%
-1.3 pp
2%
3
GPTBot
2.2%
7.7%
+5.5 pp
305%
4
ClaudeBot
11.7%
5.4%
-6.3 pp
-46%
5
GoogleOther
4.4%
4.3%
-0.1 pp
14%
6
Amazonbot
7.6%
4.2%
-3.4 pp
-35%
7
Googlebot-Image
4.5%
3.3%
-1.2 pp
-13%
8
Bytespider
22.8%
2.9%
-19.8 pp
-85%
9
Yandex
2.8%
2.2%
-0.7 pp
-10%
10
ChatGPT-User
0.1%
1.3%
+1.2 pp
2,825%
11
Applebot
1.9%
1.2%
-0.7 pp
-26%
12
Timpibot
0.3%
0.6%
+0.3 pp
133%
13
Baiduspider
0.5%
0.4%
-0.1 pp
7%
14
PerplexityBot
<0.01%
0.2%
+0.2 pp
157,490%
15
DuckDuckBot
0.2%
0.1%
-0.1 pp
-16%
16
SeznamBot
0.1%
0.1%
2%
17
Yeti
0.1%
0.1%
47%
18
coccocbot
0.1%
0.1%
-3%
19
Sogou
0.1%
0.1%
-22%
20
Yahoo! Slurp
0.1%
0.0%
-0.1 pp
-8%
Based on this data, two major shifts in web crawling occurred between May 2024 and May 2025:
1. Some AI crawlers rose sharply. GPTBot (from OpenAI) increased its share from 2.2% to 7.7% (+5.5 pp), with a 305% rise in requests. This underscores the data demand for training large language models like ChatGPT. GPTBot jumped from #9 in May 2024 to #3 in May 2025.
Another OpenAI crawler, ChatGPT-User, saw requests surge by 2,825%, reaching a 1.3% share. This reflects a large rise in ChatGPT user activity or API-based interactions that involve accessing web content. PerplexityBot (from Perplexity.ai), despite a small 0.2% share, recorded the highest growth rate: a staggering 157,490% increase in raw requests.
Meanwhile, some AI crawlers saw steep declines. ClaudeBot (Anthropic) fell from 11.7% to 5.4% of total traffic and dropped 46% in requests. Bytespider plummeted 85% in request volume, falling from #2 to #8 in crawler share (now at just 2.9%).
Both Amazonbot and Applebot, also considered AI crawlers, saw decreases in share and in raw requests (–35% and –26%, respectively).
2. Google’s dominance expanded. Googlebot’s share rose from 30% to 50%, supporting search indexing, but potentially also having AI-related purposes (such as new AI Overviews in Google Search). And GoogleOther (the crawler introduced in 2023) also increased in crawling traffic, 14%. Other Google crawlers not in the top 20, like Googlebot-News, also grew significantly (+71% in requests). There’s a clear trend of growth in these Google-related web crawlers at a time when the company is investing heavily in combining AI with search.
Also in the search category, Bingbot’s share (from Microsoft) declined slightly from 10% to 8.7% (-1.3 pp), though its raw requests still grew modestly by 2%.
These trends show that web crawling is increasingly dominated by bots from Google and OpenAI, reflecting clear shifts over the course of a year. Google also appears to be adapting how it collects data to support both traditional search and AI-driven features.
Also worth noting is FriendlyCrawler, which no longer appears in the top 20 list as of May 2025 (now ranked #35). It was #14 in May 2024 with a 0.2% share, but saw a 100% drop in requests by May 2025. This bot is known to index and analyze website content, although its owner and purpose remain unclear. Typically, crawlers like this are used for improving search results, market research, or analytics.
robots.txt & AI bots: GPTBot leads twice
Recent data from June 6, 2025, from Cloudflare Radar shows that out of 3,816 domains (from the top 10,000) where we were able to find a robots.txt file, 546 (about 14%) had “allow” or “disallow” (fully or partially) directives targeting AI bots in particular.
This leaves many site owners in a gray area because it’s not always clear how effective robots.txt is in managing AI crawlers. Some site owners may not think to use it specifically for AI bots, while others might be unsure whether these bots even respect robots.txt rules, especially newer or less transparent crawlers. In other cases, sites use partial rules to fine-tune access, trying to balance visibility and protection without fully opting in or out.
The “disallow” rules appear far more often than “allow” rules. The most frequently blocked bot was GPTBot, disallowed by 312 domains (250 fully, 62 partially), followed by CCBot and Google-Extended, as shown in the following graph.
Although GPTBot was the most blocked, it was also the most explicitly allowed, with 61 domains granting access (18 fully, 43 partially). Still, very few sites openly and explicitly allow AI bots, and when they do, it’s usually for limited sections. Note that bots not listed in a site’s robots.txt are effectively allowed by default.
As AI crawling increases, more websites are moving from passive signals like robots.txt to active protections like Web Application Firewalls. The ecosystem is shifting, with a growing focus on enforceable controls.
Note: When we analyze crawler traffic, we compare user-agent tokens found in robots.txt files (like those for AI crawlers) with the actual user-agent strings in HTTP requests. It’s important to note that some robots.txt tokens, such as Google-Extended, aren’t user-agent substrings. As described in RFC 9309, one goal of these token may be to signal the purpose of the crawler. For instance, Google uses Google-Extended in robots.txt to see if your content can be used for AI training, but the traffic itself still comes from standard Google user-agents like Googlebot. Because of this, not every robots.txt entry will have a direct match in HTTP request logs.
Conclusion
As AI crawlers reshape the Internet, websites face both new challenges and new opportunities in managing their online presence.
This analysis highlights the growing impact of AI on web crawling, showing a clear shift from traditional search indexing to data collection for training AI models. The detailed statistics, such as Googlebot’s continued growth and the rapid rise of AI-specific crawlers, offer context for understanding how this space is evolving and what it means for the future of web content access.
The trend toward stronger, enforceable blocking methods, something Cloudflare has also been invested, signals a key shift in how websites may control their interactions with AI systems going forward.
Many publishers, content creators and website owners currently feel like they have a binary choice — either leave the front door wide open for AI to consume everything they create, or create their own walled garden. But what if there was another way?
At Cloudflare, we started from a simple principle: we wanted content creators to have control over who accesses their work. If a creator wants to block all AI crawlers from their content, they should be able to do so. If a creator wants to allow some or all AI crawlers full access to their content for free, they should be able to do that, too. Creators should be in the driver’s seat.
After hundreds of conversations with news organizations, publishers, and large-scale social media platforms, we heard a consistent desire for a third path: They’d like to allow AI crawlers to access their content, but they’d like to get compensated. Currently, that requires knowing the right individual and striking a one-off deal, which is an insurmountable challenge if you don’t have scale and leverage.
What if I could charge a crawler?
We believe your choice need not be binary — there should be a third, more nuanced option: You can charge for access. Instead of a blanket block or uncompensated open access, we want to empower content owners to monetize their content at Internet scale.
We’re excited to help dust off a mostly forgotten piece of the web: HTTP response code 402.
Introducing pay per crawl
Pay per crawl, in private beta, is our first experiment in this area.
Pay per crawl integrates with existing web infrastructure, leveraging HTTP status codes and established authentication mechanisms to create a framework for paid content access.
Each time an AI crawler requests content, they either present payment intent via request headers for successful access (HTTP response code 200), or receive a 402 Payment Required response with pricing. Cloudflare acts as the Merchant of Record for pay per crawl and also provides the underlying technical infrastructure.
Publisher controls and pricing
Pay per crawl grants domain owners full control over their monetization strategy. They can define a flat, per-request price across their entire site. Publishers will then have three distinct options for a crawler:
Allow: Grant the crawler free access to content.
Charge: Require payment at the configured, domain-wide price.
Block: Deny access entirely, with no option to pay.
An important mechanism here is that even if a crawler doesn’t have a billing relationship with Cloudflare, and thus couldn’t be charged for access, a publisher can still choose to ‘charge’ them. This is the functional equivalent of a network level block (an HTTP 403 Forbidden response where no content is returned) — but with the added benefit of telling the crawler there could be a relationship in the future.
While publishers currently can define a flat price across their entire site, they retain the flexibility to bypass charges for specific crawlers as needed. This is particularly helpful if you want to allow a certain crawler through for free, or if you want to negotiate and execute a content partnership outside the pay per crawl feature.
To ensure integration with each publisher’s existing security posture, Cloudflare enforces Allow or Charge decisions via a rules engine that operates only after existing WAF policies and bot management or bot blocking features have been applied.
Payment headers and access
As we were building the system, we knew we had to solve an incredibly important technical challenge: ensuring we could charge a specific crawler, but prevent anyone from spoofing that crawler. Thankfully, there’s a way to do this using Web Bot Auth proposals.
Once registration is accepted, crawler requests should always include signature-agent, signature-input, and signature headers to identify your crawler and discover paid resources.
Once a crawler is set up, determination of whether content requires payment can happen via two flows:
Reactive (discovery-first)
Should a crawler request a paid URL, Cloudflare returns an HTTP 402 Payment Required response, accompanied by a crawler-price header. This signals that payment is required for the requested resource.
The crawler can then decide to retry the request, this time including a crawler-exact-price header to indicate agreement to pay the configured price.
GET /example.html
crawler-exact-price: USD XX.XX
Proactive (intent-first)
Alternatively, a crawler can preemptively include a crawler-max-price header in its initial request.
GET /example.html
crawler-max-price: USD XX.XX
If the price configured for a resource is equal to or below this specified limit, the request proceeds, and the content is served with a successful HTTP 200 OK response, confirming the charge:
HTTP 200 OK
crawler-charged: USD XX.XX
server: cloudflare
If the amount in a crawler-max-price request is greater than the content owner’s configured price, only the configured price is charged. However, if the resource’s configured price exceeds the maximum price offered by the crawler, an HTTP402 Payment Required response is returned, indicating the specified cost. Only a single price declaration header, crawler-exact-price or crawler-max-price, may be used per request.
The crawler-exact-price or crawler-max-price headers explicitly declare the crawler’s willingness to pay. If all checks pass, the content is served, and the crawl event is logged. If any aspect of the request is invalid, the edge returns an HTTP 402 Payment Required response.
Financial settlement
Crawler operators and content owners must configure pay per crawl payment details in their Cloudflare account. Billing events are recorded each time a crawler makes an authenticated request with payment intent and receives an HTTP 200-level response with a crawler-charged header. Cloudflare then aggregates all the events, charges the crawler, and distributes the earnings to the publisher.
Content for crawlers today, agents tomorrow
At its core, pay per crawl begins a technical shift in how content is controlled online. By providing creators with a robust, programmatic mechanism for valuing and controlling their digital assets, we empower them to continue creating the rich, diverse content that makes the Internet invaluable.
We expect pay per crawl to evolve significantly. It’s very early: we believe many different types of interactions and marketplaces can and should develop simultaneously. We are excited to support these various efforts and open standards.
For example, a publisher or new organization might want to charge different rates for different paths or content types. How do you introduce dynamic pricing based not only upon demand, but also how many users your AI application has? How do you introduce granular licenses at internet scale, whether for training, inference, search, or something entirely new?
The true potential of pay per crawl may emerge in an agentic world. What if an agentic paywall could operate entirely programmatically? Imagine asking your favorite deep research program to help you synthesize the latest cancer research or a legal brief, or just help you find the best restaurant in Soho — and then giving that agent a budget to spend to acquire the best and most relevant content. By anchoring our first solution on HTTP response code 402, we enable a future where intelligent agents can programmatically negotiate access to digital resources.
Getting started
Pay per crawl is currently in private beta. We’d love to hear from you if you’re either a crawler interested in paying to access content or a content creator interested in charging for access. You can reach out to us at http://www.cloudflare.com/paypercrawl-signup/ or contact your Account Executive if you’re an existing Enterprise customer.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.