polyfill.io, a popular JavaScript library service, can no longer be trusted and should be removed from websites.
Multiple reports, corroborated with data seen by our own client-side security system, Page Shield, have shown that the polyfill service was being used, and could be used again, to inject malicious JavaScript code into users’ browsers. This is a real threat to the Internet at large given the popularity of this library.
We have, over the last 24 hours, released an automatic JavaScript URL rewriting service that will rewrite any link to polyfill.io found in a website proxied by Cloudflare to a link to our mirror under cdnjs. This will avoid breaking site functionality while mitigating the risk of a supply chain attack.
Any website on the free plan has this feature automatically activated now. Websites on any paid plan can turn on this feature with a single click.
You can find this new feature under Security ⇒ Settings on any zone using Cloudflare.
Contrary to what is stated on the polyfill.io website, Cloudflare has never recommended the polyfill.io service or authorized their use of Cloudflare’s name on their website. We have asked them to remove the false statement and they have, so far, ignored our requests. This is yet another warning sign that they cannot be trusted.
If you are not using Cloudflare today, we still highly recommend that you remove any use of polyfill.io and/or find an alternative solution. And, while the automatic replacement function will handle most cases, the best practice is to remove polyfill.io from your projects and replace it with a secure alternative mirror like Cloudflare’s even if you are a customer.
You can do this by searching your code repositories for instances of polyfill.io and replacing it with cdnjs.cloudflare.com/polyfill/ (Cloudflare’s mirror). This is a non-breaking change as the two URLs will serve the same polyfill content. All website owners, regardless of the website using Cloudflare, should do this now.
How we came to this decision
Back in February, the domain polyfill.io, which hosts a popular JavaScript library, was sold to a new owner: Funnull, a relatively unknown company. At the time, we were concerned that this created a supply chain risk. This led us to spin up our own mirror of the polyfill.io code hosted under cdnjs, a JavaScript library repository sponsored by Cloudflare.
The new owner was unknown in the industry and did not have a track record of trust to administer a project such as polyfill.io. The concern, highlighted even by the original author, was that if they were to abuse polyfill.io by injecting additional code to the library, it could cause far reaching security problems on the Internet affecting several hundreds of thousands websites. Or it could be used to perform a targeted supply-chain attack against specific websites.
Unfortunately, that worry came true on June 25, 2024 as the polyfill.io service was being used to inject nefarious code that, under certain circumstances, redirected users to other websites.
We have taken the exceptional step of using our ability to modify HTML on the fly to replace references to the polyfill.io CDN in our customers’ websites with links to our own, safe, mirror created back in February.
In the meantime, additional threat feed providers have also taken the decision to flag the domain as malicious. We have not outright blocked the domain through any of the mechanisms we have because we are concerned it could cause widespread web outages given how broadly polyfill.io is used with some estimates indicating usage on nearly 4% of all websites.
Corroborating data with Page Shield
The original report indicates that malicious code was injected that, under certain circumstances, would redirect users to betting sites. It was doing this by loading additional JavaScript that would perform the redirect, under a set of additional domains which can be considered Indicators of Compromise (IoCs):
(note the intentional misspelling of Google Analytics)
Page Shield, our client side security solution, is available on all paid plans. When turned on, it collects information about JavaScript files loaded by end user browsers accessing your website.
By looking at the database of detected JavaScript files, we immediately found matches with the IoCs provided above starting as far back as 2024-06-08 15:23:51 (first seen timestamp on Page Shield detected JavaScript file). This was a clear indication that malicious activity was active and associated with polyfill.io.
Replacing insecure JavaScript links to polyfill.io
To achieve performant HTML rewriting, we need to make blazing-fast HTML alterations as responses stream through Cloudflare’s network. This has been made possible by leveraging ROFL (Response Overseer for FL). ROFL powers various Cloudflare products that need to alter HTML as it streams, such as Cloudflare Fonts,Email Obfuscation and Rocket Loader
ROFL is developed entirely in Rust. The memory-safety features of Rust are indispensable for ensuring protection against memory leaks while processing a staggering volume of requests, measuring in the millions per second. Rust’s compiled nature allows us to finely optimize our code for specific hardware configurations, delivering performance gains compared to interpreted languages.
The performance of ROFL allows us to rewrite HTML on-the-fly and modify the polyfill.io links quickly, safely, and efficiently. This speed helps us reduce any additional latency added by processing the HTML file.
If the feature is turned on, for any HTTP response with an HTML Content-Type, we parse all JavaScript script tag source attributes. If any are found linking to polyfill.io, we rewrite the src attribute to link to our mirror instead. We map to the correct version of the polyfill service while the query string is left untouched.
The logic will not activate if a Content Security Policy (CSP) header is found in the response. This ensures we don’t replace the link while breaking the CSP policy and therefore potentially breaking the website.
Default on for free customers, optional for everyone else
Cloudflare proxies millions of websites, and a large portion of these sites are on our free plan. Free plan customers tend to have simpler applications while not having the resources to update and react quickly to security concerns. We therefore decided to turn on the feature by default for sites on our free plan, as the likelihood of causing issues is reduced while also helping keep safe a very large portion of applications using polyfill.io.
Paid plan customers, on the other hand, have more complex applications and react quicker to security notices. We are confident that most paid customers using polyfill.io and Cloudflare will appreciate the ability to virtually patch the issue with a single click, while controlling when to do so.
All customers can turn off the feature at any time.
This isn’t the first time we’ve decided a security problem was so widespread and serious that we’d enable protection for all customers regardless of whether they were a paying customer or not. Back in 2014, we enabled Shellshock protection for everyone. In 2021, when the log4j vulnerability was disclosed we rolled out protection for all customers.
Do not use polyfill.io
If you are using Cloudflare, you can remove polyfill.io with a single click on the Cloudflare dashboard by heading over to your zone ⇒ Security ⇒ Settings. If you are a free customer, the rewrite is automatically active. This feature, we hope, will help you quickly patch the issue.
Nonetheless, you should ultimately search your code repositories for instances of polyfill.io and replace them with an alternative provider, such as Cloudflare’s secure mirror under cdnjs (https://cdnjs.cloudflare.com/polyfill/). Website owners who are not using Cloudflare should also perform these steps.
Last week, we announced the general availability of custom AWS service blueprints, a new feature in Amazon DataZone allowing you to customize your Amazon DataZone project environments to use existing AWS Identity and Access Management (IAM) roles and AWS services to embed the service into your existing processes. In this post, we share how this new feature can help you in federating to your existing AWS resources using your own IAM role. We also delve into details on how to configure data sources and subscription targets for a project using a custom AWS service blueprint.
New feature: Custom AWS service blueprints
Previously, Amazon DataZone provided default blueprints that created AWS resources required for data lake, data warehouse, and machine learning use cases. However, you may have existing AWS resources such as Amazon Redshift databases, Amazon Simple Storage Service (Amazon S3) buckets, AWS Glue Data Catalog tables, AWS Glue ETL jobs, Amazon EMR clusters, and many more for your data lake, data warehouse, and other use cases. With Amazon DataZone default blueprints, you were limited to only using preconfigured AWS resources that Amazon DataZone created. Customers needed a way to integrate these existing AWS service resources with Amazon DataZone, using a customized IAM role so that Amazon DataZone users can get federated access to those AWS service resources and use the publication and subscription features of Amazon DataZone to share and govern them.
Now, with custom AWS service blueprints, you can use your existing resources using your preconfigured IAM role. Administrators can customize Amazon DataZone to use existing AWS resources, enabling Amazon DataZone portal users to have federated access to those AWS services to catalog, share, and subscribe to data, thereby establishing data governance across the platform.
Benefits of custom AWS service blueprints
Custom AWS service blueprints don’t provision any resources for you, unlike other blueprints. Instead, you can configure your IAM role (bring your own role) to integrate your existing AWS resources with Amazon DataZone. Additionally, you can configure action links, which provide federated access to any AWS resources like S3 buckets, AWS Glue ETL jobs, and so on, using your IAM role.
You can also configure custom AWS service blueprints to bring your own resources, namely AWS databases, as data sources and subscription targets to enhance governance across those assets. With this release, administrators can configure data sources and subscription targets on the Amazon DataZone console and not be restricted to do those actions in the data portal.
Custom blueprints and environments can only be set up by administrators to manage access to configured AWS resources. As custom environments are created in specific projects, the right to grant access to custom resources is delegated to the project owners who can manage project membership by adding or removing members. This restricts the ability of portal users to create custom environments without the right permissions in AWS Console for Amazon DataZone or access custom AWS resources configured in a project that they are not a member of.
Solution overview
To get started, administrators need to enable the custom AWS service blueprints feature on the Amazon DataZone console. Then administrators can customize configurations by defining which project and IAM role to use when federating to the AWS services that are set up as action links for end-users. After the customized set up is complete, when a data producer or consumer logs in to the Amazon DataZone portal and if they’re part of those customized projects, they can federate to any of the configured AWS services such as Amazon S3 to upload or download files or seamlessly go to existing AWS Glue ETL jobs using their own IAM roles and continue their work with data with the customized tool of choice. With this feature, you can how include Amazon DataZone in your existing data pipeline processes to catalog, share, and govern data.
The following diagram shows an administrator’s workflow to set up a custom blueprint.
In the following sections, we discuss common use cases for custom blueprints, and walk through the setup step by step. If you’re new to Amazon DataZone, refer to Getting started.
Use case 1: Bring your own role and resources
Customers manage data platforms that consist of AWS managed services such as AWS Lake Formation, Amazon S3 for data lakes, AWS Glue for ETL, and so on. With those processes already set up, you may want to bring your own roles and resources to Amazon DataZone to continue with an existing process without any disruption. In such cases, you may not want Amazon DataZone to create new resources because it disrupts existing processes in data pipelines and to also curtail AWS resource usage and costs.
In the current setup, you can create an Amazon DataZone domain associated with different accounts. There could be a dedicated account that acts like a producer to share data, and a few other consumer accounts to subscribe to published assets in the catalog. The consumer account has IAM permissions set up for the AWS Glue ETL job to use for the subscription environment of a project. By doing so, the role has access to the newly subscribed data as well as permissions from previous setups to access data from other AWS resources. After you configure the AWS Glue job IAM role in the environment using the custom AWS service blueprint, the authorized users of that role can use the subscribed assets in the AWS Glue ETL job and extend that data for downstream activities to store them in Amazon S3 and other databases to be queried and analyzed using the Amazon Athena SQL editor or Amazon QuickSight.
Use case 2: Amazon S3 multi-file downloads
Customers and users of the Amazon DataZone portal often need the ability to download files after searching and filtering through the catalog in an Amazon DataZone project. This requirement arises because the data and analytics associated with a particular use case can sometimes involve hundreds of files. Downloading these files individually would be a tedious and time-consuming process for Amazon DataZone users. To address this need, the Amazon DataZone portal can take advantage of the capabilities provided by custom AWS service blueprints. These custom blueprints allow you to configure action links to S3 bucket folders associated with specified Amazon DataZone projects.
You can build projects and subscribe to both unstructured and structured data assets within the Amazon DataZone portal. For structured datasets, you can use Amazon DataZone blueprint-based environments like data lakes (Athena) and data warehouses (Amazon Redshift). For unstructured data assets, you can use the custom blueprint-based Amazon S3 environment, which provides a familiar Amazon S3 browser interface with access to specific buckets and folders, using an IAM role owned and provided by the customer. This functionality streamlines the process of finding and accessing unstructured data and allows you to download multiple files at once, enabling you to build and enhance your analytics more efficiently.
Use case 3: Amazon S3 file uploads
In addition to the download functionality, users often need to retain and attach metadata to new versions of files. For example, when you download a file, you can perform data changes, enrichment, or analysis on the file, and then upload the updated version back to the Amazon DataZone portal. For uploading files, Amazon DataZone users can use the same custom blueprint-based Amazon S3 environment action links to upload files.
Use case 4: Extend existing environments to custom blueprint environments
You may have existing Amazon DataZone project environments created using default data lake and data warehouse blueprints. With other AWS services set up in the data platform, you may want to extend the configured project environments to include those additional services to provide a seamless experience for your data producers or consumers while switching between tools.
Now that you understand the capabilities of the new feature, let’s look at how administrators can set up a custom role and resources on the Amazon DataZone console.
Create a domain
First, you need an Amazon DataZone domain. If you already have one, you can skip to enabling your custom blueprints. Otherwise, refer to Create domains for instructions to set up a domain. Optionally, you can associate accounts if you want to set up Amazon DataZone across multiple accounts.
Associate accounts for cross-account scenarios
You can optionally associate accounts. For instructions, refer to Request association with other AWS accounts. Make sure to use the latest AWS Resource Access Manager (AWS RAM) DataZonePortalReadWrite policy when requesting account association. If your account is already associated, request access again with the new policy.
Add associated account users in the Amazon DataZon domain account
With this launch, you can set up associated account owners to access the Amazon DataZone data portal from their account. To enable this, they need to be registered as users in the domain account. As a domain admin, you can create Amazon DataZone user profiles to allow Amazon DataZone access to users and roles from the associated account. Complete the following steps:
On the Amazon DataZone console, navigate to your domain.
On the User management tab, choose Add IAM Users from the Add dropdown menu.
Enter the ARNs of your associated account IAM users or roles. For this post, we add arn:aws:iam::123456789101:role/serviceBlueprintRole and arn:aws:iam::123456789101:user/Jacob.
Choose Add users(s).
Back on the User management tab, you should see the new user state with Assigned status. This means that the domain owner has assigned associated account users to access Amazon DataZone. This status will change to Active when the identity starts using Amazon DataZone from the associated account.
As of writing this post, there is a maximum limit of adding six identities (users or roles) per associated account.
Enable the custom AWS service blueprint feature
You can enable custom AWS service blueprints in the domain account or the associated account, according to your requirements. Complete the following steps:
On the Account associations tab, choose the associated domain.
Choose the AWS service blueprint.
Choose Enable.
Create an environment using the custom blueprint
If an associated account is being used to create this environment, use the same associated account IAM identity assigned by the domain owner in the previous step. Your identity needs to be explicitly assigned a user profile in order for you to create this environment. Complete the following steps:
Choose the custom blueprint.
In the Created environments section, choose Create environment.
Select Create and use a new project or use an existing project if you already have one.
For Environment role, choose a role. For this post, we curated a cross-account role called AmazonDataZoneAdmin and gave it AdministratorAccess This is the bring your own role feature. You should curate your role according to your requirements. Here are some guidelines on how to set up custom role as we have used a more permissible policy for this blog:
You can use AWS Policy Generator to build a policy that fits your requirements and attach it to the custom IAM role you want to use.
Make sure the role begins with AmazonDataZone* to follow conventions. This is not mandatory, but recommended. If the IAM admin is using an AmazonDataZoneFullAccess policy, you need to follow this convention because there is a pass role check validation.
When you create the CustomRole (AWSDataZone*) make sure it trusts amazonaws.com in its trust policy:
Although you could use the same IAM role for multiple environments in a project, the recommendation is to not use a same IAM role for multiple environments across projects. Subscription grants are fulfilled at the project construct and therefore we don’t allow the same environment role to be used across different projects.
Configure custom action links
After you create the AWS service environment, you can configure any AWS Management Console links to your environment. Amazon DataZone will assume the custom role to help federate environment users to the configured action links. Complete the following steps:
In your environment, choose Customize AWS links.
Configure any S3 buckets, Athena workgroups, AWS Glue jobs, or other custom resources.
Select Custom AWS links and enter any AWS service console custom resources. For this post, we link to the Amazon Relational Database Service (Amazon RDS) console.
You should now see the console links set up for your environment.
Access resources using a custom role through the Amazon DataZone portal from an associated account
Associate account users who have been added to Amazon DataZone can access the data portal from their associated account directly. Complete the following steps:
In your environment, in the Summary section, choose the My Environment link.
You should see all your configured resources (role and action links) for your environment.
Choose any action link to navigate to the appropriate console resources.
Choose any action link for a custom resource (for this post, Amazon RDS).
You’re directed to the appropriate service console.
With this setup, you have now configured a custom AWS service blueprint to use your own role for the environment to use for data access as well. You have also set up action links for configured AWS resources to be shown to data producers and consumers in the Amazon DataZone data portal. With these links, you can federate to those services in a single click and take the project context along while working with the data.
Configure data sources and subscription targets
Additionally, administrators can now configure data sources and subscription targets on the Amazon DataZone console using custom AWS service blueprint environments. This needs to be configured to set up the database role ManagedAccessRole to the data source and subscription target, which you can’t do through the Amazon DataZone portal.
Configure data sources in the custom AWS service blueprint environment for publishing
Complete the following steps to configure your data source:
On the Amazon DataZone console, navigate to the custom AWS service blueprint environment you just created.
On the Data sources tab, choose Add
Select AWS Glue or Amazon Redshift.
For AWS Glue, complete the following steps:
Enter your AWS Glue database. If you don’t already have an existing AWS Glue database setup, refer to Create a database.
Enter the manageAccessRole role that is added as a Lake Formation admin. Make sure the role provided has aws.internal in its trust policy. The role starts with AmazonDataZone*.
Choose Add.
For Amazon Redshift, complete the following steps:
Choose Create new AWS Secret or use a preexisting one.
If you’re creating a new secret, enter a secret name, user name, and password.
Choose the cluster or workgroup you want to connect to.
Enter the database and schema names.
Enter the role ARN for manageAccessRole.
Choose Add.
Configure a subscription target in the AWS service environment for subscribing
Complete the following steps to add your subscription target
On the Amazon DataZone console, navigate the custom AWS service blueprint environment you just created.
On the Subscription targets tab, choose Add.
Follow the same steps as you did to set up a data source.
For Redshift subscription targets, you also need to add a database role that will be granted access to the given schema. You can enter a specific Redshift user role or, if you’re a Redshift admin, enter sys:superuser.
Create a new tag on the environment role (BYOR) with RedshiftDbRoles as key and the database name used for configuring the Redshift subscription target as value.
Extend existing data lake and data warehouse blueprints
Finally, if you want to extend existing data lake or data warehouse project environments to create to use existing AWS services in the platform, complete the following steps:
Create a copy of the environment role of an existing Amazon DataZone project environment.
Extend this role by adding additional required policies to allow this custom role to access additional resources.
Create a custom AWS service environment in the same Amazon DataZone project using this new custom role.
Configure the subscription target and data source using the database name of the existing Amazon DataZone environment (<env_name>_pub_db, <env_name>_sub_db).
Use the same managedAccessRole role from the existing Amazon DataZone environment.
Request subscription to the required data assets or add subscribed assets from the project to this new AWS service environment.
Clean up
To clean up your resources, complete the following steps:
If you used sample code for AWS Glue and Redshift databases, make sure to clean up all those resources to avoid incurring additional charges. Delete any S3 buckets you created as well.
On the Amazon DataZone console, delete the projects used in this post. This will delete most project-related objects like data assets and environments.
On the Lake Formation console, delete the Lake Formation admins registered by Amazon DataZone.
On the Lake Formation console, delete any tables and databases created by Amazon DataZone.
Conclusion
In this post, we discussed how the custom AWS service blueprint simplifies the process to start using existing IAM roles and AWS services in Amazon DataZone for end-to-end governance of your data in AWS. This integration helps you circumvent the prescriptive default data lake and data warehouse blueprints.
To learn more about Amazon DataZone and how to get started, refer to the Getting started guide. Check out the YouTube playlist for some of the latest demos of Amazon DataZone and more information about the capabilities available.
About the Authors
Anish Anturkar is a Software Engineer and Designer and part of Amazon DataZone with an expertise in distributed software solutions. He is passionate about building robust, scalable, and sustainable software solutions for his customers.
Navneet Srivastava is a Principal Specialist and Analytics Strategy Leader, and develops strategic plans for building an end-to-end analytical strategy for large biopharma, healthcare, and life sciences organizations. Navneet is responsible for helping life sciences organizations and healthcare companies deploy data governance and analytical applications, electronic medical records, devices, and AI/ML-based applications, while educating customers about how to build secure, scalable, and cost-effective AWS solutions. His expertise spans across data analytics, data governance, AI, ML, big data, and healthcare-related technologies.
Priya Tiruthani is a Senior Technical Product Manager with Amazon DataZone at AWS. She focuses on improving data discovery and curation required for data analytics. She is passionate about building innovative products to simplify customers’ end-to-end data journey, especially around data governance and analytics. Outside of work, she enjoys being outdoors to hike, capture nature’s beauty, and recently play pickleball.
Subrat Das is a Senior Solutions Architect and part of the Global Healthcare and Life Sciences industry division at AWS. He is passionate about modernizing and architecting complex customer workloads. When he’s not working on technology solutions, he enjoys long hikes and traveling around the world.
The Rapid7 Take Command summit unveiled crucial findings from the 2024 Attack Intelligence Report, offering invaluable insights for cybersecurity professionals navigating today’s complex threat landscape.
Key takeaways from the 30 minute panel:
Rise of Zero-Day Exploits: 53% of mass compromise events in 2023 and early 2024 began with zero-day exploits. This highlights the urgent need for improved patch management and proactive defense strategies.
Network Edge Vulnerabilities: Over a third of the vulnerabilities leading to mass compromise events were in network edge technologies, such as firewalls and VPNs, emphasizing the importance of securing these critical points.
Ransomware on the Rise: Rapid7 tracked over 5,600 ransomware incidents in 2023 and early 2024, with ransomware payouts exceeding $1 billion. The sheer volume underscores the importance of robust defenses and incident response plans.
Key Quote:
“Our research shows that more than 40% of incident responses in 2023 stemmed from remote remote access exploits without multifactor authentication. Basic security components are still crucial in making attacks harder.” – Caitlin Condon, Director Vulnerability Intelligence, Rapid7
The 2024 Attack Intelligence Report provides deep insights into the evolving threat landscape, highlighting the rise of zero-day exploits, the critical vulnerabilities in network edge technologies, and the rampant increase in ransomware incidents, you can view it here.
For a deeper dive into these findings, click through to watch the full video and stay ahead of attackers.
The openSUSE project has announced
Leap Micro version
6.0. Leap Micro is an image-based, lightweight Linux distribution
that is designed to run containerized and virtualized applications. It
is based on SUSE Linux
Enterprise (SLE) Micro. Changes in this release include the
support for full-disk encryption, the addition of Cockpit for
web-based system management, and an optional real-time kernel for
x86_64. Boot support for legacy BIOS on x86_64 is deprecated with 6.0, and will be removed in a later release. See the SLE
Micro release notes for more information.
Peter Hutterer has written
a summary of “papercut fixes” for GNOME tablet support that are
planned to ship with GNOME 47.
If you’re an avid tablet user, you may have multiple stylus tools –
but it’s also likely that you have multiple tools of the same type
which makes differentiating them in the GUI hard. Which is why they’re
highlighted now – if you bring the tool into proximity, the matching
image is highlighted to make it easier to know which stylus you’re
about to configure. Oh, and in the process we added a new SVG for AES
styli too to make the picture look more like the actual physical
tool. The <blink> tag may no longer be cool but at least we can disco
our way through the stylus configuration now.
After several public betas, we launchedAmazon Simple Queue Service (Amazon SQS) in 2006. Nearly two decades later, this fully managed service is still a fundamental building block for microservices, distributed systems, and serverless applications, processing over 100 million messages per second at peak times.
Because there’s always a better way, we continue to look for ways to improve performance, security, internal efficiency, and so forth. When we do find a potential way to do something better, we are careful to preserve existing behavior, and often run new and old systems in parallel to allow us to compare results.
Today I would like to tell you how we recently made improvements to Amazon SQS to reduce latency, increase fleet capacity, mitigate an approaching scalability cliff, and reduce power consumption.
Improving SQS Like many AWS services, Amazon SQS is implemented using a collection of internal microservices. Let’s focus on two of them today:
Customer Front-End – The customer-facing front-end accepts, authenticates, and authorizes API calls such as CreateQueue and SendMessage. It then routes each request to the storage back-end.
Storage Back-End -This internal microservice is responsible for persisting messages sent to standard (non-FIFO) queues. Using a cell-based model, each cluster in the cell contains multiple hosts, each customer queue is assigned to one or more clusters, and each cluster is responsible for a multitude of queues:
Connections – Old and New The original implementation used a connection per request between these two services. Each front-end had to connect to many hosts, which mandated the use of a connection pool, and also risked reaching an ultimate, hard-wired limit on the number of open connections. While it is often possible to simply throw hardware at problems like this and scale out, that’s not always the best way. It simply moves the moment of truth (the “scalability cliff”) into the future and does not make efficient use of resources.
After carefully considering several long-term solutions, the Amazon SQS team invented a new, proprietary binary framing protocol between the customer front-end and storage back-end. The protocol multiplexes multiple requests and responses across a single connection, using 128-bit IDs and checksumming to prevent crosstalk. Server-side encryption provides an additional layer of protection against unauthorized access to queue data.
It Works! The new protocol was put into production earlier this year and has processed 744.9 trillion requests as I write this. The scalability cliff has been eliminated and we are already looking for ways to put this new protocol to work in other ways.
Performance-wise, the new protocol has reduced dataplane latency by 11% on average, and by 17.4% at the P90 mark. In addition to making SQS itself more performant, this change benefits services that build on SQS as well. For example, messages sent through Amazon Simple Notification Service (Amazon SNS) now spend 10% less time “inside” before being delivered. Finally, due to the protocol change, the existing fleet of SQS hosts (a mix of X86 and Graviton-powered instances) can now handle 17.8% more requests than before.
More to Come I hope that you have enjoyed this little peek inside the implementation of Amazon SQS. Let me know in the comments, and I will see if I can find some more stories to share.
Eric Sandeen led a filesystem-track session at
the
2024 Linux Storage,
Filesystem, Memory Management, and BPF Summit on completing the
conversion of the existing kernel filesystems to use the mount API that was added for the 5.2 kernel in 2019. That API is
invariably called the “new” API, which it is when compared to the
venerable mount()
system call, but it has been available for five years or so at this point
without really pushing its predecessor aside. Sandeen wanted to discuss
the status of the conversion process and some other questions surrounding
the new API.
The Rust Blog is carrying an
update on what the Rust Types Team has been up to and its near-future
plans.
There has been a
lot of work on the next-generation
trait solver. The initiative posted a
separate update at the end of last year. While we would have
liked to stabilize its
use in coherence a few months ago, this surfaced additional
small behavior regressions and hangs, causing delays. We are
working on fixing these issues and intend to merge the
stabilization PR soon. We are getting close to compiling the
standard library and the compiler with the new solver enabled
everywhere, after which will be able to run crater to figure out
the remaining issues.
Security updates have been issued by AlmaLinux (git, python3.11, and python3.9), Debian (chromium, emacs, git, linux-5.10, and org-mode), Fedora (libopenmpt, nginx-mod-modsecurity, and thunderbird), Mageia (emacs, python-ansible-core, and python-authlib), Oracle (git, python3.11, and python3.9), Red Hat (kernel, kernel-rt, and samba), and Ubuntu (ansible, cups, google-guest-agent, google-osconfig-agent, libheif, openvpn, roundcube, and salt).
On Thursday, June 20, 2024, two independent events caused an increase in latency and error rates for Internet properties and Cloudflare services that lasted 114 minutes. During the 30-minute peak of the impact, we saw that 1.4 – 2.1% of HTTP requests to our CDN received a generic error page, and observed a 3x increase for the 99th percentile Time To First Byte (TTFB) latency.
A new Distributed Denial-of-Service (DDoS) mitigation mechanism deployed between 14:14 and 17:06 UTC triggered a latent bug in our rate limiting system that allowed a specific form of HTTP request to cause a process handling it to enter an infinite loop between 17:47 and 19:27 UTC
Impact from these events were observed in many Cloudflare data centers around the world.
With respect to the backbone congestion event, we were already working on expanding backbone capacity in the affected data centers, and improving our network mitigations to use more information about the available capacity on alternative network paths when taking action. In the remainder of this blog post, we will go into more detail on the second and more impactful of these events.
As part of routine updates to our protection mechanisms, we created a new DDoS rule to prevent a specific type of abuse that we observed on our infrastructure. This DDoS rule worked as expected, however in a specific suspect traffic case it exposed a latent bug in our existing rate-limiting component. To be absolutely clear, we have no reason to believe this suspect traffic was intentionally exploiting this bug, and there is no evidence of a breach of any kind.
We are sorry for the impact and have already made changes to help prevent these problems from occurring again.
Background
Rate-limiting suspicious traffic
Depending on the profile of an HTTP request and the configuration of the requested Internet property, Cloudflare may protect our network and our customer’s origins by applying a limit to the number of requests a visitor can make within a certain time window. These rate limits can activate through customer configuration or in response to DDoS rules detecting suspicious activity.
Usually, these rate limits will be applied based on the IP address of the visitor. As many institutions and Internet Service Providers (ISPs) can have many devices and individual users behind a single IP address, rate limiting based on the IP address is a broad brush that can unintentionally block legitimate traffic.
Balancing traffic across our network
Cloudflare has several systems that together provide continuous real-time capacity monitoring and rebalancing to ensure we serve as much traffic as we can as quickly and efficiently as we can.
The first of these is Unimog, Cloudflare’s edge load balancer. Every packet that reaches our anycast network passes through Unimog, which delivers it to an appropriate server to process that packet. That server may be in a different location from where the packet originally arrived into our network, depending on the availability of compute capacity. Within each data center, Unimog aims to keep the CPU load uniform across all active servers.
For a global view of our network, we rely on Traffic Manager. Across all of our data center locations, it takes in a variety of signals, such as overall CPU utilization, HTTP request latency, and bandwidth utilization to instruct rebalancing decisions. It has built-in safety limits to prevent causing outsized traffic shifts, and also considers the expected resulting load in destination locations when making any decisions.
Incident timeline and impact
All timestamps are UTC on 2024-06-20.
14:14 DDoS rule gradual deployment starts
17:06 DDoS rule deployed globally
17:47 First HTTP request handling processe is poisoned
18:04 Incident declared automatically based on detected high CPU load
18:34 Service restart shown to recover on a server, full restart tested in one data center
18:44 CPU load normalized in data center after service restart
18:51 Continual global reloads of all servers with many stuck processes begin
19:05 Global eyeball HTTP error rate peaks at 2.1% service unavailable / 3.45% total
19:05 First Traffic Manager actions recovering service
19:11 Global eyeball HTTP error rate halved to 1% service unavailable / 1.96% total
19:27 Global eyeball HTTP error rate reduced to baseline levels
19:29 DDoS rule deployment identified as likely cause of process poisoning
19:34 DDoS rule is fully disabled
19:43 Engineers stop routine restarts of services on servers with many stuck processes
20:16 Incident response stood down
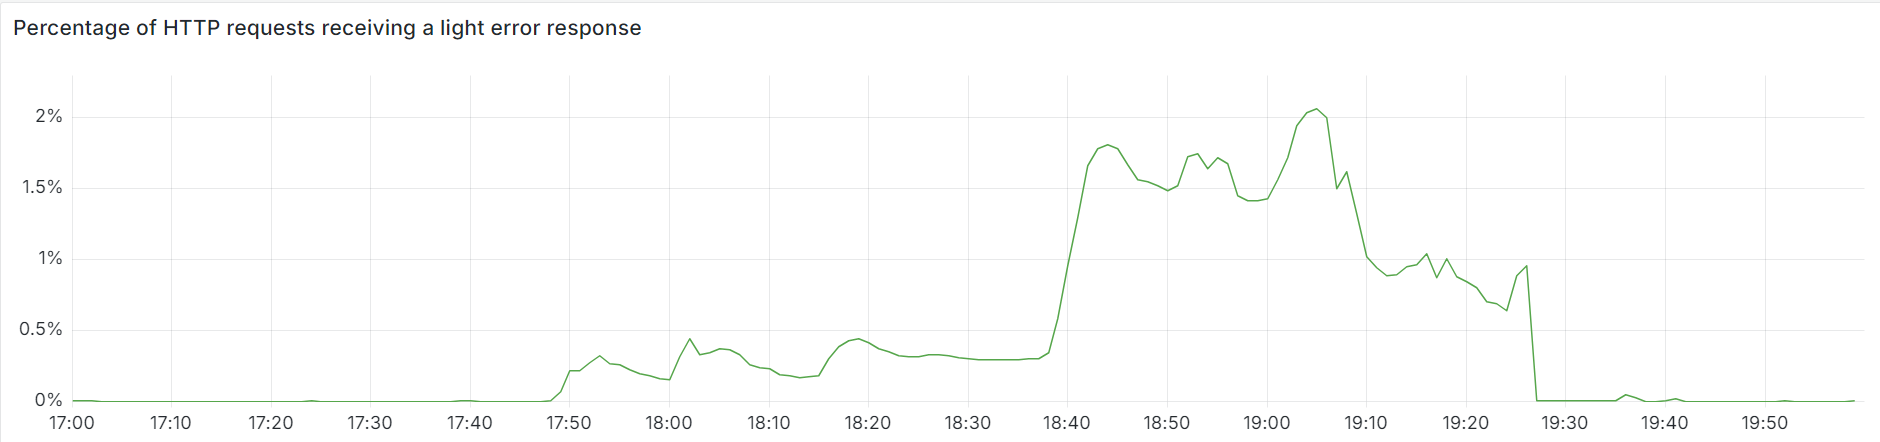
Below, we provide a view of the impact from some of Cloudflare’s internal metrics. The first graph illustrates the percentage of all eyeball (inbound from external devices) HTTP requests that were served an error response because the service suffering poisoning could not be reached. We saw an initial increase to 0.5% of requests, and then later a larger one reaching as much as 2.1% before recovery started due to our service reloads.
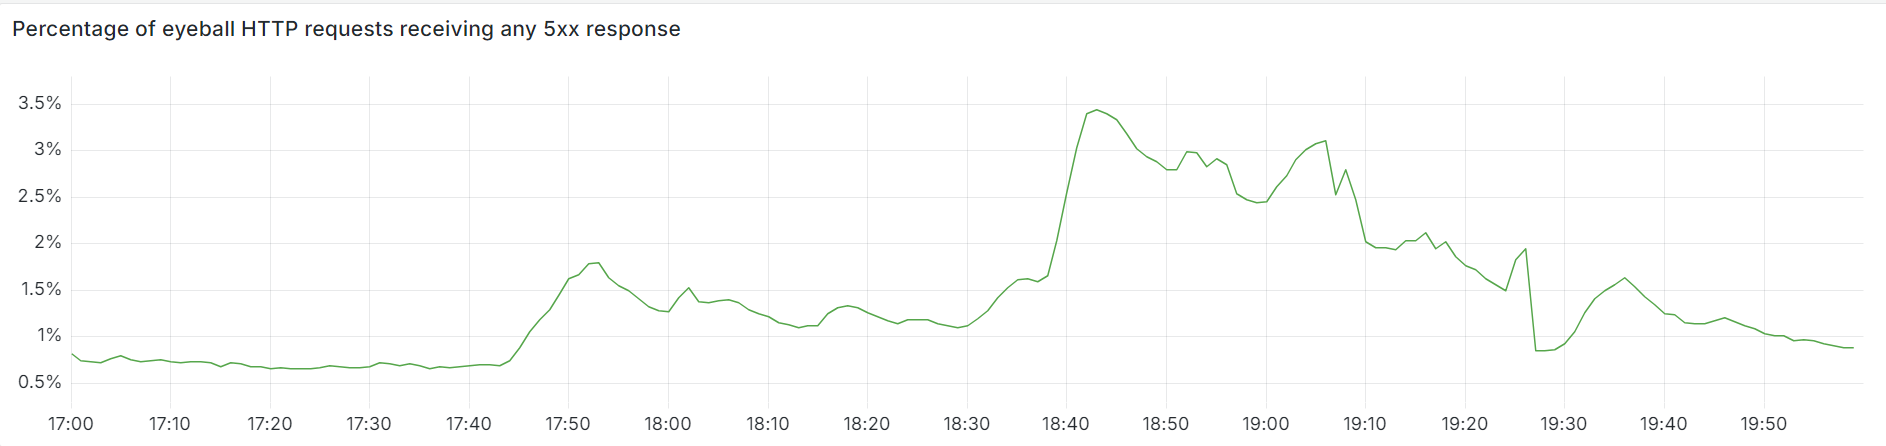
For a broader view of errors, we can see all 5xx responses our network returned to eyeballs during the same window, including those from origin servers. These peaked at 3.45%, and you can more clearly see the gradual recovery between 19:25 and 20:00 UTC as Traffic Manager finished its re-routing activities. The dip at 19:25 UTC aligns with the last large reload, with the error increase afterwards primarily consisting of upstream DNS timeouts and connection limits which are consistent with high and unbalanced load.
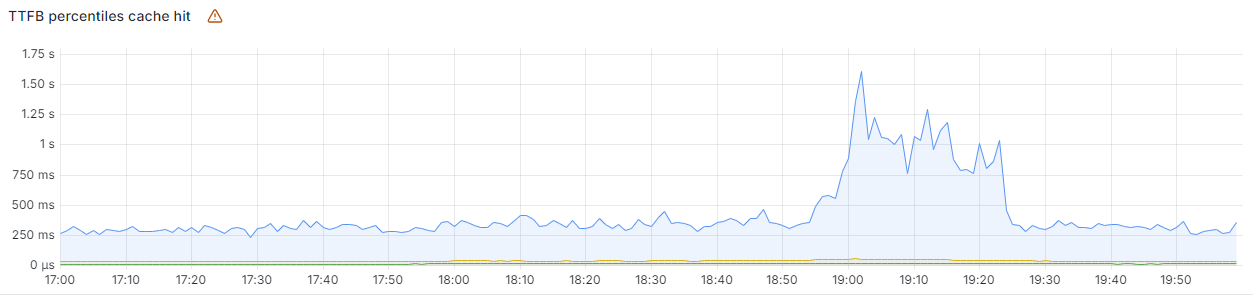
And here’s what our TTFB measurements looked like at the 50th, 90th and 99th percentiles, showing an almost 3x increase in latency at p99:
Technical description of the error and how it happened
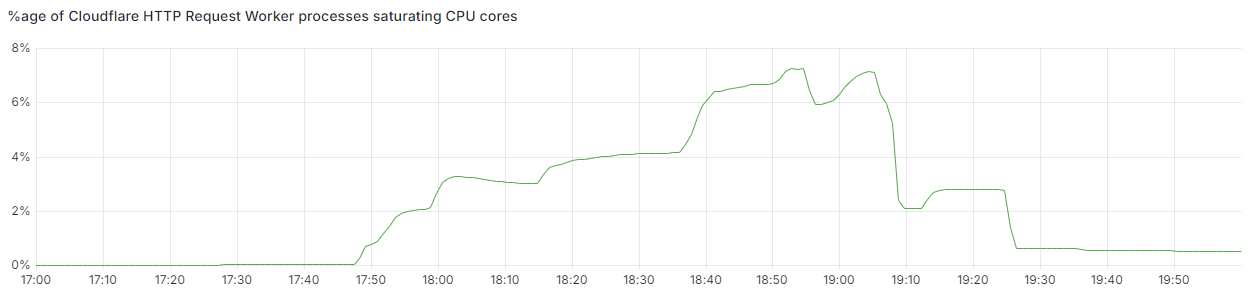
Global percentage of HTTP Request handling processes that were using excessive CPU during the event
Earlier on June 20, between 14:14 – 17:06 UTC, we gradually activated a new DDoS rule on our network. Cloudflare has recently been building a new way of mitigating HTTP DDoS attacks. This method is using a combination of rate-limits and cookies in order to allow legitimate clients that were falsely identified as being part of an attack to proceed anyway.
With this new method, an HTTP request that is considered suspicious runs through these key steps:
Check for the presence of a valid cookie, otherwise block the request
If a valid cookie is found, add a rate-limit rule based on the cookie value to be evaluated at a later point
Once all the currently applied DDoS mitigation are run, apply rate-limit rules
We use this “asynchronous” workflow because it is more efficient to block a request without a rate-limit rule, so it gives a chance for other rule types to be applied.
So overall, the flow can be summarized with this pseudocode:
for (rule in active_mitigations) {
   // ... (ignore other rule types)
   if (rule.match_current_request()) {
       if (!has_valid_cookie()) {
           // no cookie: serve error page
           return serve_error_page();
       } else {
           // add a rate-limit rule to be evaluated later
           add_rate_limit_rule(rule);
       }
   }
}


evaluate_rate_limit_rules();
When evaluating rate-limit rules, we need to make a key for each client that is used to look up the correct counter and compare it with the target rate. Typically, this key is the client IP address, but other options are available, such as the value of a cookie as used here. We actually reused an existing portion of the rate-limit logic to achieve this. In pseudocode, it looks like:
function get_cookie_key() {
   // Validate that the cookie is valid before taking its value.
   // Here the cookie has been checked before already, but this code is
   // also used for "standalone" rate-limit rules.
   if (!has_valid_cookie_broken()) { // more on the "broken" part later
       return cookie_value;
   } else {
       return parent_key_generator();
   }
}
This simple key generation function had two issues that, combined with a specific form of client request, caused an infinite loop in the process handling the HTTP request:
The rate-limit rules generated by the DDoS logic are using internal APIs in ways that haven’t been anticipated. This caused the parent_key_generator in the pseudocode above to point to the get_cookie_key function itself, meaning that if that code path was taken, the function would call itself indefinitely
As these rate-limit rules are added only after validating the cookie, validating it a second time should give the same result. The problem is that the has_valid_cookie_broken function used here is actually different and both can disagree if the client sends multiple cookies where some are valid but not others
So, combining these two issues: the broken validation function tells get_cookie_key that the cookie is invalid, causing the else branch to be taken and calling the same function over and over.
A protection many programming languages have in place to help prevent loops like this is a run-time protection limit on how deep the stack of function calls can get. An attempt to call a function once already at this limit will result in a runtime error. When reading the logic above, an initial analysis might suggest we were reaching the limit in this case, and so requests eventually resulted in an error, with a stack containing those same function calls over and over.
However, this isn’t the case here. Some languages, including Lua, in which this logic is written, also implement an optimization called proper tail calls. A tail call is when the final action a function takes is to execute another function. Instead of adding that function as another layer in the stack, as we know for sure that we will not be returning execution context to the parent function afterwards, nor using any of its local variables, we can replace the top frame in the stack with this function call instead.
The end result is a loop in the request processing logic which never increases the size of the stack. Instead, it simply consumes 100% of available CPU resources, and never terminates. Once a process handling HTTP requests receives a single request on which the action should be applied and has a mixture of valid and invalid cookies, that process is poisoned and is never able to process any further requests.
Every Cloudflare server has dozens of such processes, so a single poisoned process does not have much of an impact. However, then some other things start happening:
The increase in CPU utilization for the server causes Unimog to lower the amount of new traffic that server receives, moving traffic to other servers, so at a certain point, more new connections are directed away from servers with a subset of their processes poisoned to those with fewer or no poisoned processes, and therefore lower CPU utilization.
The gradual increase in CPU utilization in the data center starts to cause Traffic Manager to redirect traffic to other data centers. As this movement does not fix the poisoned processes, CPU utilization remains high, and so Traffic Manager continues to redirect more and more traffic away.
The redirected traffic in both cases includes the requests that are poisoning processes, causing the servers and data centers to which this redirected traffic was sent to start failing in the same way.
Within a few minutes, multiple data centers had many poisoned processes, and Traffic Manager had redirected as much traffic away from them as possible, but was restricted from doing more. This was partly due to its built-in automation safety limits, but also because it was becoming more difficult to find a data center with sufficient available capacity to use as a target.
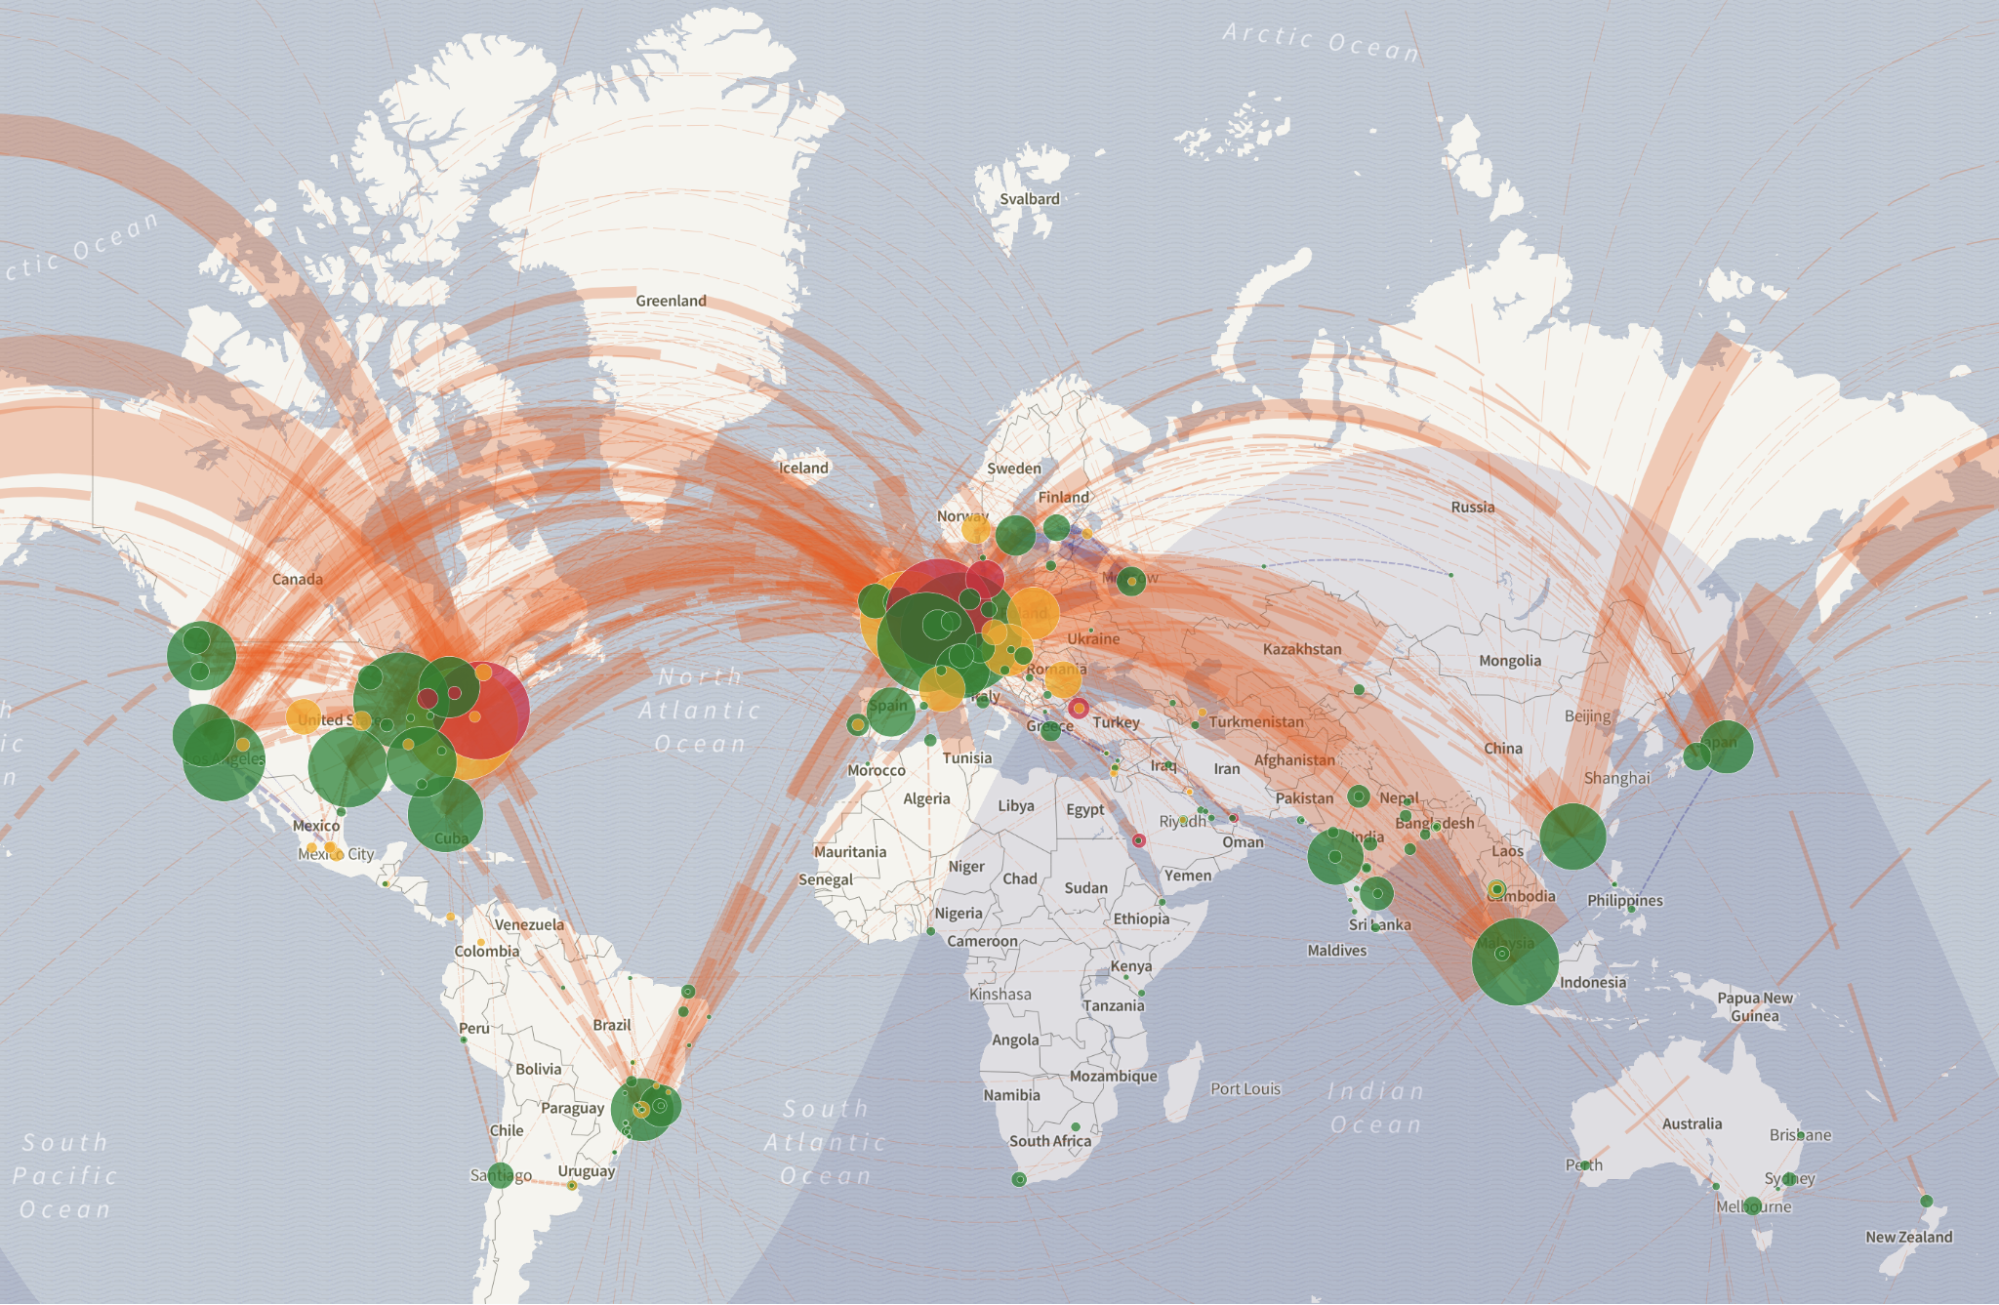
The first case of a poisoned process was at 17:47 UTC, and by 18:09 UTC – five minutes after the incident was declared – Traffic Manager was re-routing a lot of traffic out of Europe:
A summary map of Traffic Manager capacity actions as of 18:09 UTC. Each circle represents a data center that traffic is being re-routed towards or away from. The color of the circle indicates the CPU load of that data center. The orange ribbons between them show how much traffic is re-routed, and where from/to.
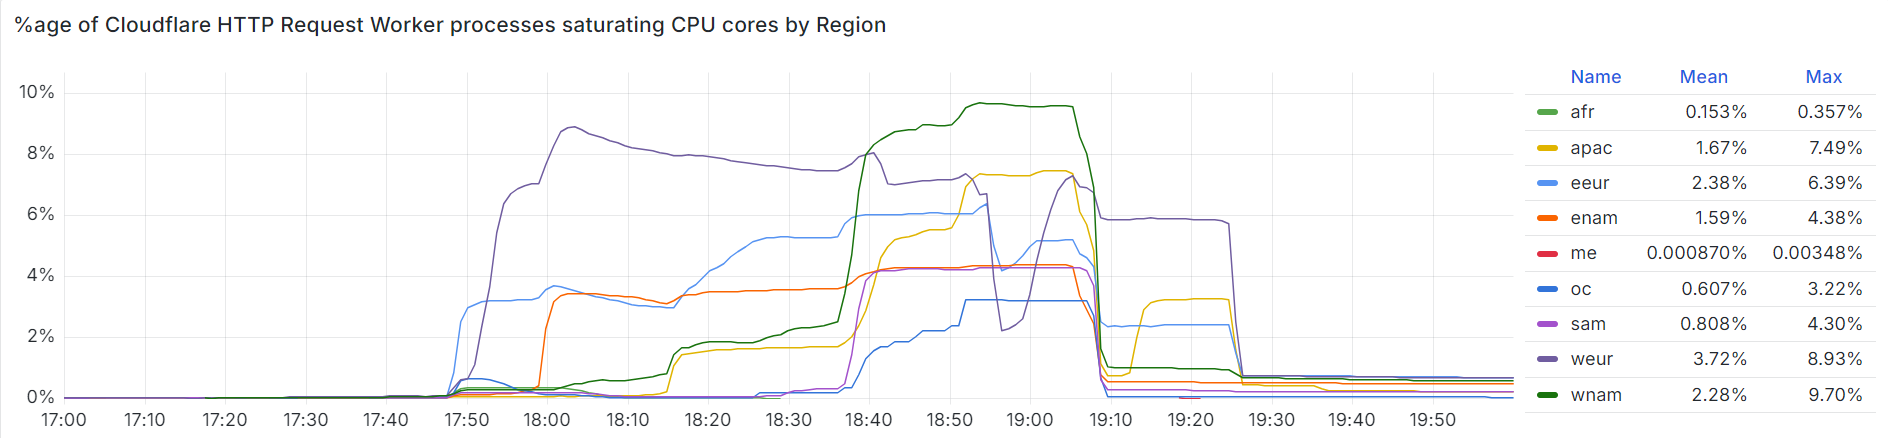
It’s obvious to see why, if we look at the percentage of the HTTP request service’s processes that were saturating their CPUs. 10% of our capacity in Western Europe was already gone, and 4% in Eastern Europe, during peak traffic time for those timezones:
Percentage of all the HTTP request handling processes saturating their CPU, by geographic region
Partially poisoned servers in many locations struggled with the request load, and the remaining processes could not keep up, resulting in Cloudflare returning minimal HTTP error responses.
Cloudflare engineers were automatically notified at 18:04 UTC, once our global CPU utilization reached a certain sustained level, and started to investigate. Many of our on-duty incident responders were already working on the open incident caused by backbone network congestion, and in the early minutes we looked into likely correlation with the network congestion events. It took some time for us to realize that locations where the CPU was highest is where traffic was the lowest, drawing the investigation away from a network event being the trigger. At this point, the focus moved to two main streams:
Evaluating if restarting poisoned processes allowed them to recover, and if so, instigating mass-restarts of the service on affected servers
Identifying the trigger of processes entering this CPU saturation state
It was 25 minutes after the initial incident was declared when we validated that restarts helped on one sample server. Five minutes after this, we started executing wider restarts – initially to entire data centers at once, and then as the identification method was refined, on servers with a large number of poisoned processes. Some engineers continued regular routine restarts of the affected service on impacted servers, whilst others moved to join the ongoing parallel effort to identify the trigger. At 19:36 UTC, the new DDoS rule was disabled globally, and the incident was declared resolved after executing one more round of mass restarts and monitoring.
At the same time, conditions presented by the incident triggered a latent bug in Traffic Manager. When triggered, the system would attempt to recover from the exception by initiating a graceful restart, halting its activity. The bug was first triggered at 18:17 UTC, then numerous times between 18:35 and 18:57 UTC. During two periods in this window (18:35-18:52 UTC and 18:56-19:05 UTC) the system did not issue any new traffic routing actions. This meant whilst we had recovered service in the most affected data centers, almost all traffic was still being re-routed away from them. Alerting notified on-call engineers of the issue at 18:34 UTC. By 19:05 UTC the Traffic team had written, tested, and deployed a fix. The first actions following restoration showed a positive impact on restoring service.
Remediation and follow-up steps
To resolve the immediate impact to our network from the request poisoning, Cloudflare instigated mass rolling restarts of the affected service until the change that triggered the condition was identified and rolled back. The change, which was the activation of a new type of DDoS rule, remains fully rolled back, and the rule will not be reactivated until we have fixed the broken cookie validation check and are fully confident this situation cannot recur.
We take these incidents very seriously, and recognize the magnitude of impact they had. We have identified several steps we can take to address these specific situations, and the risk of these sorts of problems from recurring in the future.
Design: The rate limiting implementation in use for our DDoS module is a legacy component, and rate limiting rules customers configure for their Internet properties use a newer engine with more modern technologies and protections.
Design: We are exploring options within and around the service which experienced process poisoning to limit the ability to loop forever through tail calls. Longer term, Cloudflare is entering the early implementation stages of replacing this service entirely. The design of this replacement service will allow us to apply limits on the non-interrupted and total execution time of a single request.
Process: The activation of the new rule for the first time was staged in a handful of production data centers for validation, and then to all data centers a few hours later. We will continue to enhance our staging and rollout procedures to minimize the potential change-related blast radius.
Conclusion
Cloudflare experienced two back-to-back incidents that affected a significant set of customers using our CDN and network services. The first was network backbone congestion that our systems automatically remediated. We mitigated the second by regularly restarting the faulty service whilst we identified and deactivated the DDoS rule that was triggering the fault. We are sorry for any disruption this caused our customers and to end users trying to access services.
The conditions necessary to activate the latent bug in the faulty service are no longer possible in our production environment, and we are putting further fixes and detections in place as soon as possible.
The Biden administration on Thursday said it’s banning the company from selling its products to new US-based customers starting on July 20, with the company only allowed to provide software updates to existing customers through September 29. The ban—the first such action under authorities given to the Commerce Department in 2019—follows years of warnings from the US intelligence community about Kaspersky being a national security threat because Moscow could allegedly commandeer its all-seeing antivirus software to spy on its customers.
Еми Барух беше в Израел и се върна оттам с три материала, които ще споделим в „Тоест“ в три последователни седмици. Започваме с интервюто ѝ със световноизвестния израелски писател Етгар Керет и ще продължим с репортажи от протестите срещу управлението на Нетаняху и от опустошените кибуци, сцена на зверствата от октомври 2023 г.
Етгар Керет е един от най-популярните съвременни израелски писатели. Автор е на множество разкази, графични романи и сценарии за кино и телевизия. Роден е в Рамат Ган, Израел, през 1967 г. в семейството на хора, оцелели от Холокоста. Снимка: Lielle Sand
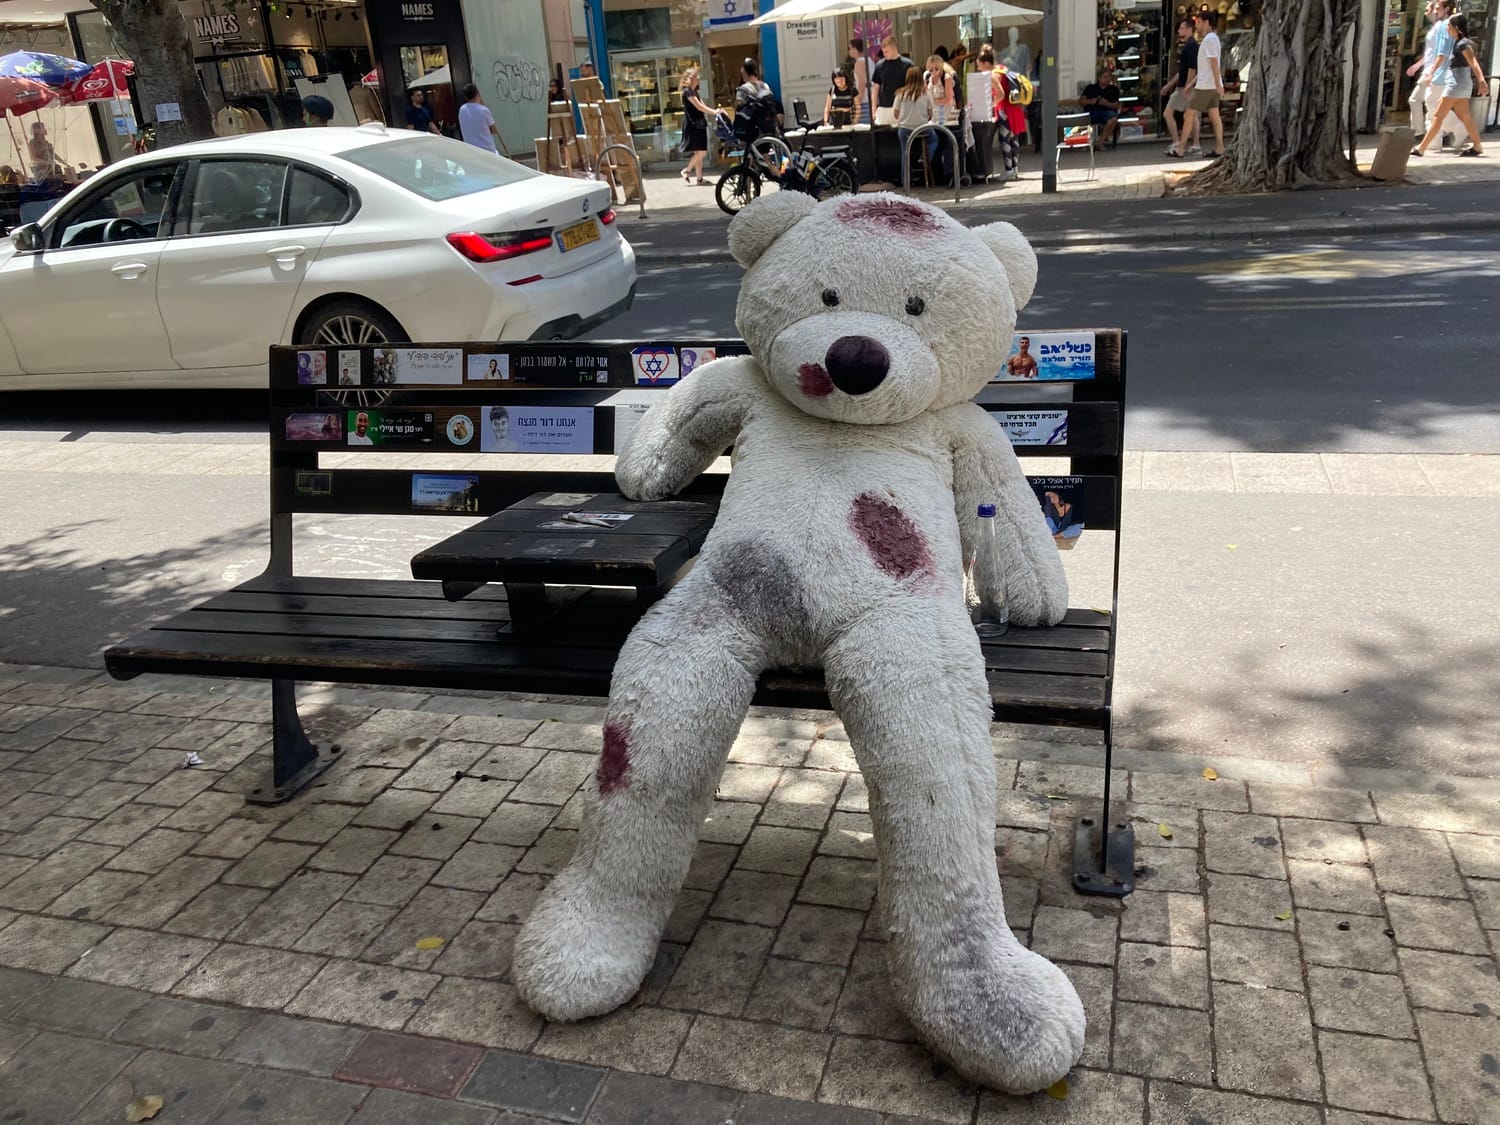
Върху пейките на улица „Дизенгоф“ в Тел Авив са поставени големи бели плюшени мечета с тъмночервени петна по козината, напомнящи на кръв. На облегалките са залепени снимки на отвлечените в Газа заложници. Бяха минали 222 дни от 7 октомври 2023 г.
На една от тези пейки пред малък цветарски магазин чакам Етгар Керет. Всички вестници вече писаха за най-новата му книга Autocorrect. Писаха още, че Етгар Керет никога не е мълчал толкова дълго. Разговорът ни започва от това мълчание.
За милионите Ваши читатели Вие сте забележителен автор, който умее да смесва магическото и всекидневното и да превръща голямата картина в разбираем разказ за живота. Свикнали сме да търсим ориентири за случващото се тук във всички Ваши кратки разкази, есета, графични романи, филми. Ще ги намерим ли в най-новата Ви книга?
Странна е тази история. Когато работя върху една книга, винаги има дата, на която трябва да я предам в издателството. Преди това сядам, чета и се питам искам ли тази книга да бъде публикувана, не трябва ли да поработя още над нея.
Денят, в който трябваше да предам Autocorrect, беше 8 октомври 2023 г. Започнах да чета финалната версия на 6-ти.
Писах книгата по време на коронавируса, по време на протестите срещу Нетаняху и опитите му да промени правосъдната система в страната. И най-вече след като загубих майка си, която беше наистина най-близкият ми човек. За мен това бяха трудни времена.
Когато на 6 октомври стигнах до средата на книгата, казах на жена ми: „Не съм сигурен, че ще я предам на 8 октомври, защото историите са добри, но в тях има нещо много песимистично, много тъмно. Струва ми се, че заради моята лична загуба показвам една доста мрачна картина на света.“
Жена ми отговори: „Ти винаги прекалено много мислиш! Но ако наистина така го чувстваш, остави книгата настрана, отиди да направиш нещо приятно, наспи се, а утре я прочети отново и ако имаш същите съмнения, не я предавай в издателството.“
Аз си казах „ОК“. И я оставих.
На 7 октомври се събудих рано от ракетите и всичко останало… Изобщо забравих за книгата. Сетих се за нея през януари. Прочетох я отново и си помислих: „О, тя е чудесна. На 6 октомври ми се стори, че е прекалено мрачна, а след 7 октомври сякаш всичко си дойде точно на мястото.“
Мече на улица „Дизенгоф“ в Тел Авив. Снимка: Еми Барух
На кое точно място? Вие къде се озовахте след 7 октомври?
Когато всичко започна, хората, които можеха най-много да помогнат, бяха тези, които умеят да карат кола и да приготвят храна. А това са две неща, с които никак не се справям. Винаги съм си мислил, че е много секси така – не умея да шофирам, не мога да готвя… Гаджетата ще ме возят, ще ходим на ресторант. След 7 октомври се почувствах виновен, питах се как ще помагам, като не карам кола.
Тогава с жена ми започнахме да посещаваме местата, където евакуираха оцелелите от кибуците. Отивахме при тях и им казвахме: „Ако искате, ще поиграем с децата; ако искате, ще ви разказвам истории, ще бъдем заедно.“ Нямаше значение дали там има сто души, или са само трима.
В съботата след 7 октомври отидохме в най-тежко пострадалия кибуц. Посрещна ни една висока жена, която държеше съвсем малко бебе. Беше страшно мила, помогна ни, стоя повече от два-три часа с нас.
Накрая, когато ни съпроводи до колата, се сетих, че не съм я попитал за името ѝ… Два часа по-късно беше вече неудобно да я питам. Казах ѝ: „Вие сте късметлийка с толкова спокойно бебе. Как се казва детенцето?“ Тя ме погледна и отвърна: „Не знам. Не съм от кибуца. Дойдох току-що, за да помагам. Имаше една жена, която кърмеше бебето си. В този момент дойдоха да ѝ съобщят, че са намерили тялото на мъжа ѝ, когото е мислила за отвлечен, а е бил убит. Тя припадна. И аз взех бебето.“
Разбирате ли? Не съм способен да интерпретирам действителността. Толкова е сложно, толкова е объркано. И всеки, който заяви „Това доказва единствено еди-какво си“, значи нищо не е разбрал.
Ще ви разкажа и една друга история. Потърси ме 19-годишен войник. Беше загубил крака си в Газа, където бе воювал, и когато ми се обади, ми каза, че иска да разкаже своята история, но не знае как. Отвърнах му, че мога да опитам да помогна, да го посъветвам и т.н.
Беше много вълнуваща среща за мен и когато на връщане се качих в таксито, се опитах да споделя с шофьора. Казах му: „Срещнах се с един войник, толкова е млад, трудно ходи, а е в началото на живота си, как ще си намери приятелка, работа, как ще я кара нататък…“
Виждам, че на шофьора не му пука, гледа ме някак ядосано. И си помислих, че може би той също е загубил някого. Всички страдаме, цялата страна страда, всички преживяваме. А той – руски емигрант – ми казва: „На мен ли ще ми обясняваш!“ И започна да разказва своята история.
Взели го пет дни запас. На 7 октомври ги отвели на юг и ги закарали на мястото на фестивала Nova. Трябвало да събират телата. И ми разказва за телата, за положението, в което са лежали, ужасяващи неща, които няма да повторя, неща, които остават в теб.
Истината е, че не исках да слушам, но слушах. Той завърши с думите: „Кажи ми честно, дали човек, видял всичко това, може да спи нощем?“
Аз отговорих: „Не.“ А той продължи: „Да, така е. Не мога да спя. И трябва да ти разкажа какво ми се случи тази сутрин. В 5 часа качих едно момиче близо до клуб „Хавана“. И тази млада жена, на 24 години, седна на задната седалка и от момента, в който се настани, не престана да се оплаква: „Отивам в този бар, купувам си питие – 70 шекела, представяш ли си?! Това са почти 20 долара! Как е възможно! В пластмасова чаша слагат малко водка и ти взeмат 70 шекела. Трябва да си оставя палтото – 20 шекела! Ненормални хора! Всичко е скъпо, искат да ме разорят!“
Шофьорът продължи: „Когато карам, нямам нерви за такива разговори, но си казвам: „Това ти е работата, човече, не се разправяй, мълчи си и карай.“ Докато не спрях на светофара и тя не каза: „Писнало ми е от всички тези алчни пъбове, отсега нататък – само партита на открито!“ Мигом се обърнах към нея като озверял вълк, сякаш щях да я ухапя. Казах ѝ: „Ти къде си мислиш, че живееш?“ В този момент очите ни се срещнаха. И си спомних как, когато събирах телата, в един момент усетих движение, помислих, че е плъх, но после видях, че под труповете имаше млада жена, която беше оцеляла. Попитах момичето в таксито: „Ти беше ли на Nova?“. То ме погледна, усмихна се и отвърна: „Аз те помня…“
Може да си помислим, че това момиче е психопатка, социопатка, че е будистка, йога, може да кажем: „Този човек е сбъркан. Човече, отивай да спиш, видял си всичко това, а сега – живей в настоящето.“
Не знам какъв е правилният отговор. Но цялата тази бъркотия е реалността, в която живеем. Мисля, че проблемът е, че толкова много хора искат да е просто и ясно. Но то не е. То е мътно, объркано, пълно с противоречиви моменти. И ти виждаш както много човечност, така и липсата ѝ, виждаш расизъм.
Аз събирам истории, но не мога да ги обобщя. Мисля, че моята работа като писател не е да представям на хората някакви дидактични наративи. А по-скоро, ако някой ми разкаже нещо за определена ситуация, да му кажа: „Да, това е истина, но има и друга истина.“
Каква е другата истина, която казвате на хората, твърдящи, че Израел извършва геноцид в Газа?
На хората, които твърдят, че сме се опитвали да извършим геноцид, искам да кажа, че след 1967 г. населението на Палестина се е увеличило 8 пъти. Ако това е геноцид, значи той е много, много неуспешен.
Когато искам да критикувам страната си, което е част от работа ми на писател, бих казал, че извършва не геноцид, а военно престъпление. Женевската конвенция постановява, че когато окупираш една територия, си отговорен за хората, които живеят там. Ако ние сме окупирали тази земя и не доставяме достатъчно хуманитарна помощ или ако твърдим, че това не е наша отговорност, от гледна точка на закона извършваме престъпление. Дали това е военно престъпление, или не, е тема за разговор. Но той приключва в момента, в който заявиш, че Израел извършва геноцид. И аз не искам да разговарям с теб.
Преди много време написах едно есе в „Ню Йорк Таймс“ за термините „пропалестинец“ и „произраелец“, обяснявайки защо ме дразнят. Ако някой ми каже „Аз съм произраелец“, той всъщност ми заявява: „Какъвто и разговор да последва, каквито и аргументи да чуя, накрая няма да променя мнението си, независимо от фактите.“ Мисля, че това е опростенчество. Така гледа светът на Израел, така е и когато израелците се опитват да разкажат собствените си истории. Не познавам човек, който да е пробългарин или антитурчин. Вие нямате такова нещо. С израелците и палестинците обаче не е така.
Аз съм израелец, но не съм произраелец. Как мога да бъда човек, който подкрепя липсата на достатъчно храна в Газа, как мога да подкрепям бомбардировките, които костват огромен брой невинни жертви? Значи ли това, че аз съм пропалестинец? Нима мога да подкрепям убийствата на цели семейства? Как да подкрепям идеология, която не се интересува, че ще бъдат пожертвани толкова много хора, защото Аллах ще ги направи велики? Не мога.
Как ще коментирате акциите на пропалестинците в кампусите на университетите от Бръшляновата лига?
Живеем в толкова дивашко време, че когато наблюдаваме едно събитие, виждаме само неговите екстремни проявления. Вярвам, че много от хората, които организират протести в кампусите, искат Палестина да е свободна. Аз също искам Палестина да е свободна. И съм участвал в много протести.
Не съм сигурен обаче, че част от онези, които пеят „От реката до морето“ – което е много романтичен рефрен, – си дават сметка, че фактически казват: „Ще разрушим страната ти и Израел няма да съществува повече.“
В тази бъркотия някои екстремисти скандират „Смърт на ционистите!“, „Искаме да умрете!“, „Тази страна ще бъде наша“, но те не съзнават какво повтарят. Нито познават географията.
Има две концепции за конфликта в Близкия изток.
Едната е религиозната, фундаменталистката. От едната страна е „Хамас“, от другата е крайнодесният министър на националната сигурност на Израел – Итамар Бен-Гвир.
Фундаменталисткото виждане е следното: „Тази земя е обещана на един народ. Можем да спорим дали на палестинците, или на израелците, но само един народ може да живее тук. А другите трябва да се махнат.“
Другата концепция е: „Има два народа и никой не трябва да се маха, следователно трябва да има две държави.“
Убеден съм, че много от демонстрантите дори не разбират разликата между намирането на решение за две държави или за една държава, което според Бен-Гвир означава евреи да строят селища в Газа, а според „Хамас“ – да бъдат убити всички израелци и да им се вземе цялата територия.
Впрочем мечтата на „Хамас“ дори не е да я има Палестина, а да се създаде нещо като ислямистка държава, която ще започне от Газа, ще мине през Израел, ще стигне до Ливан, ще се разпростре до Ирак, ще контролира Йемен. Това не е националистическа идея, това е религиозна идея. И в основата си тя е ислямистка.
Погледнете Иран – какво общо имат Иран и „Хамас“? Иранците са шиити, „Хамас“ са сунити. Иранците говорят фарси, „Хамас“ говорят арабски. Иранците не са араби. Но те искат арабите да умират заради техните вярвания. Е, какво е това, ако не колониализъм! Каква е тази война, в която пращаш на смърт „робите“ да се бият за теб?
Снимка: Lielle Sand
В едно интервю говорите за семейството си, в което има от радикални до либерални възгледи. Как се справяте с различията?
След 7 октомври различни хора се питаха как да продължат, и ми звъняха. Един казва: „Брат ми умря. Искам да отворя библиотека в негова памет, можеш ли да ми помогнеш да получа книги от различни издатели?“ Друг ми казва: „Баща ми беше на фестивала и не се знае дали е жив, не са намерили тялото му, можеш ли да ми помогнеш да говоря с хора, които се занимават с това?“ Правя всякакви такива неща, които са и депресиращи, и важни.
Когато разказвам на сестра ми, тя всеки път ми обяснява колко много се моли: „Моля се за войниците, моля се за тези, които умряха, моля се за тези, които помагат“. И го казва с една такава гордост, която ме отегчава. На кого му пука! Но тя ми е сестра и аз я обичам, тя е добър човек и просто ѝ казвам: „Виж, чувствам, че губя търпение, а ти не го заслужаваш, нека поговорим друг ден.“
Всеки път, когато изпитам подобно раздразнение, за да се отърва от него, пиша история от гледна точка на човека, който ме е ядосал. Написал съм повече от десет за Биби Нетаняху. Една от тях се казва „Най-добрият лъжец на света“. Разказът е за човек, който толкова много лъже, че вече не знае какво иска. Епична история. Но като я четеш, започваш да го съжаляваш…
Тези разкази са като упражнение, което правиш, за да влезеш в обувките на някого. Когато създаваш такъв герой, не може да напишеш: „Той е зъл, той е глупав.“ Трябва да изградиш убедителен образ. Да го очовечиш. Невинаги се получава добра история, но за мен това е като терапия.
Да се върна на сестра ми. Измислих разказ за човек, който се моли през цялото време. Такива хора вярват, че има някой от другата страна, който слуша, който разбира, който се грижи. Аз не съм вярващ. Твърде циничен съм. Докато пишех обаче, си дадох сметка, че молитвите и писането са близки. Зададох си въпроса „Кое спира хората да пишат?“. Може би се опасяват, че няма да бъдат разбрани, че никой няма да схване какво искат да кажат.
За да пишеш, трябва да повярваш, че от другата страна има някой, който се интересува от това, което имаш да кажеш.
Сестра ми се моли, аз пиша. Кой казва, че моите истории са важни, кой казва, че някой ги чете или че ги чете по начина, по който аз съм ги написал? И осъзнах, че ние и двамата искаме нещо, което може би няма да получим…
Очаквате обаче хора със съвършено различни възгледи да се научат да общуват едни с други. Има ги във Вашите разкази. В живота обаче…
Родителите ми са оцелели от Холокоста. Но слушаха Вагнер. Съседите питаха майка ми защо слуша Вагнер, при положение че нацистите са го обичали. А майка ми отговаряше: „Нацистите обичаха и щрудел. Искаш и щрудел да не ям, защото някакви проклети нацисти са обичали щрудел?“ „Не, ама Вагнер е антисемит.“ Отговорът на майка ми беше: „Ако Вагнер беше тук, бих го отровила, но музиката му е чудесна. Така че, хайде, омитай се от къщата ми. Искам да си слушам тази музика.“
Един от най-добрите приятели на моите родители беше германец, който на 18 години е бил войник в германската армия по време на Втората световна война. Не е бил есесовец, воювал е с Ромел в Северна Африка. Когато бях дете, се чудех на баща ми: „Цялата ти фамилия е избита от нацистите, как можеш да си приятел с него?“ А той ми отговори: „Опитвам се да се поставя на мястото му – ако съм млад, страната ми е във война и ме пращат да воювам за нея, ще отида и ще я защитавам. Когато виждам млад човек, който се е бил за страната си и който съжалява за това, разбирам, че е приятел. Че не е антисемит.“
Майка ми и баща ми ме научиха да не приемам политическата идентичност. Още преди да се появи това понятие. През целия ми живот родителите ми се опитваха да спорят с този идентификационен детерминизъм. Те имаха три деца. Сестра ми е ортодоксална еврейка, има единайсет деца и повече от петдесет внуци. Брат ми е антиционист. Аз съм ляв либерал. И двамата ми родители бяха с десни убеждения.
Казвам, че съм за човечността. За това, което съм научил от родителите си. И се старая да избягвам всякакви етикети, които прехвърлят на други моята морална отговорност.
Това ли е най-важният урок, който научихте от тях?
Знаете ли кое е първото, което светът иска да прехвърлим на друг? Състраданието. Живеем във време, в което ни се казва на кого трябва да съчувстваме.
Когато светът е бил по-примитивен и сме живели на село, дори някой да разказва расистки вицове, пак щях да си общувам с него. Той е единственият, който продава масло в селото. Освен това е добър човек. Когато ми се налага да отида до града, ми полива цветята. Аз хем не го харесвам, хем го харесвам, защото мога да видя неговата човещина.
Сега, когато влезеш в социалните мрежи, попадаш на нещо като пуританска идея за праведност. Не харесваме онези хора, защото те не са прави.
Ако направим дисекция на всеки човек и го анализираме, ще се окаже, че никой не е прав. Да се лъже е лошо. Аз не познавам нито един човек, който да не е лъгал. Всеки е вършил неща, за които съжалява. Ако някой ги заснеме и ги качи във Facebook, с всички нас е свършено.
Когато започна руско-украинската война, с жена ми събирахме дрехи и вещи за пострадалите. После разни хора почнаха да ме питат защо не си сменя профилната снимка с украинското знаме. Ами не мисля, че когато смениш профилната си снимка, някой в бомбоубежище в Киев автоматично ще получи повече храна или ще се почувства по-спокоен.
Ти го правиш за себе си, а не за тях.
Бях поканен да говоря на Панаира на книгата в Болоня от името на украинския народ. Там се срещнах с човек от Италианския културен институт и той ми каза: „Съчувстваме много на украинския народ, правим толкова неща за него!“ Попитах го какво правят, и той ми отговори, че е трябвало да има конференция, посветена на 100-годишнината от рождението на Достоевски, но са я спрели заради руската инвазия. Попитах го дали Достоевски е бил путинист. „Няма значение – отговори, – за руснаците той е герой.“ Чудя се как отказът да говориш за един шедьовър, който разказва за сложността на човечеството, помага на хората в скривалищата в Киев. Не знам.
В миналото нещата бяха по-ясни и действията – по-разбираеми. Ако например през 70-те години покажеш на едно извънземно активист, завързал се за дърво, препречвайки пътя на булдозер, и попиташ „Какво се случва тук?“, извънземното най-вероятно ще отговори: „Този, който се е завързал за дървото, не иска да бъде изсечена гората.“ Ако на същото извънземно му покажеш как в наши дни един човек залива с доматена супа „Мона Лиза“, и го попиташ какво иска този човек, пришълецът би казал: „Може би много мрази изкуството или не обича доматена супа.“ Но каква е връзката с глобалното затопляне?
Мога да заливам „Мона Лиза“ със супа, протестирайки срещу абортите, мога да я заливам, защитавайки абортите. Мога да заливам „Мона Лиза“ със супа против ковид ваксинациите или за ковид ваксинациите. В крайна сметка това, което правя, е да заливам „Мона Лиза“ със супа.
И когато гледам Грета Тунберг, си мисля, че това е новият модел на активист. Твърде различен от действията на големите исторически фигури като Ганди, Мартин Лутър Кинг или Роза Паркс.
Фундаменталната разлика е, първо, че всички тези хора са действали, за да променят своята непосредствена среда. Грета Тунберг говори за далечното бъдеще на своите хипотетични деца…
Второ, всички тези хора са платили своята цена. Ганди е убит. Мартин Лутър Кинг е убит. Роза е изпратена в затвора.
Грета има много последователи в Instagram, където от своя диван качи снимка „Освободете Газа“. Това е много, много лесно. Когато погледнеш профила на Грета, виждаш момиче, живеещо в една от най-привилегированите страни в света, с ограничени социални умения, на което понякога му е трудно да споделя емоциите на други хора. Това е нашият ролеви модел. Човек, който няма особено широки познания, който не е постигнал нищо, но е много хаплив и – особено за момиче на нейната възраст – твърде способен да обижда хората.
Има нещо доста опростенческо, примитивно, нарцистично в този тип активизъм. Защото той не мисли за света, а как да се представи пред света. Интересно е да се види дали тези активисти истински подкрепят каузата, зад която стоят, или всъщност действат срещу нея.
Всички хора, които месеци наред протестираха срещу правосъдната реформата на Нетаняху, истински подкрепяха тази кауза.
Ходя почти всяка седмица на тези протести, сблъсквам се с полицаите, които блокират магистралата. Брат ми си счупи крака, беше арестуван. Не съм против протестите. Ходя на тях, защото се чувствам безсилен, безпомощен, а искам да направя нещо… Не мисля, че ако не отида, ще се промени каквото и да било, но имам нужда да заявя мнението си.
Някои хора са там само за да задоволят нарцистичното си чувство за всемогъщество, без изобщо да поставят под съмнение подхода си.
И още нещо – когато си сред много хора, които скандират, може да се заблудиш, че всички мислят като теб.
След 7 октомври в Европа имаше огромни антиизраелски протести. Какъв ефект оказаха те върху войната в Газа? Много малък, даже никакъв. Ако ме питате какво постигнаха – създадоха вълна от ислямофобия в Европа, която за първи път видя каква голяма мюсюлманска общност се мобилизира на нейна територия.
Вследствие на тези протести, и то по несправедлив начин, някои страни промениха имиграционните си закони и направиха живота на бежанците по-труден. В Нидерландия например фашистка партия спечели изборите. Това нямаше да се случи, ако не бяха тези бурни демонстрации, които изплашиха хората. Несправедливо, разбира се, но те породиха негативна представа за исляма, съвсем непредставителна за тази религия.
Възможно е след две години тези, които протестираха в Колумбийския университет, да погледнат назад и да се запитат какви са били истинските последствия от техните действия. Дали са помогнали да бъде избран Тръмп? И ако е така, дали следващите избори няма да са последните, защото нов мандат на Тръмп може да сложи край на демократичното управление?
Оптимист ли сте в сегашната ситуация?
Аз съм оптимист първо по наследство, защото родителите ми са били оптимисти и са оцелели по време на Холокоста. Освен това мисля, че да си оптимист е най-добрата стратегия. Но бидейки оптимист, казвам, че това е най-мрачният период в моя живот.
Роден съм през 1967 г., преживял съм войната през 1973 г. Никога преди не съм се страхувал, че враждебна държава ще унищожи Израел. Това никога не ми се е струвало възможно. И дори след невъобразимата трагедия от 7 октомври не чувствах, че Израел е под реална заплаха. Голямата заплаха за мен – защото познавам историята – идва от самите нас.
В някакъв момент някое радикално фундаменталистко еврейско движение ще се опита да поеме контрола над страната. Водени от някаква религиозна мегаломания, тези екстремисти виждат себе си като по-висши същества… По времето на Римската империя са се гордели, че не се нуждаят от Рим. Днес вярват, че са над САЩ и Европа. И се представят като образци на добродетелта.
Идеята на Бен-Гвир за създаване на еврейски селища в ивицата Газа се възприема от около 90% от израелското население като напълно нелепа, неморална, проблематична и разрушителна. По същия начин, макар над 80 на сто от израелците да смятат, че Нетаняху трябва да подаде оставка, той остава министър-председател.
Де факто имаме коалиция между Нетаняху и [лидера на „Хамас“ – б.а.] Синуар, защото и двамата знаят много добре, че краят на войната ще сложи край на политическата им кариера. И за да задоволят личните амбиции на тези двама мъже, палестинските цивилни от Газа, населението на Северен Израел, евакуирано заради ракетните обстрели, и всички израелски граждани, изправени пред опасността от нападение и икономически колапс, плащат най-високата цена.
Това не е обикновен израелско-палестински конфликт. По същество това е сблъсък между религиозните месиански групи и нормалните хора. Умерените и от двете страни са заложници.
Юни е горещ не само температурно, но и политически. Проведоха се избори за национален и европейски парламент, разгарят се страсти около съставянето на новото правителство. И няма яснота дали такова ще се сформира, или ще ходим на избори за седми път през последните три години.
Насред летните политически страсти няколко случая на жени, които не са могли да се измъкнат живи от капана на домашното насилие, смразяват кръвта. Още повече че поне в един от тях (вероятно и в повече) фаталният изход можеше да се избегне.
Месецът още не е свършил, а от началото му поне четирима мъже в България са убили по една жена. На 3 юни 57-годишен мъж убива жена си, след което прави неуспешен опит за самоубийство. На 13 юни е убита 68-годишна жена. Заподозрян е синът ѝ, който е психичноболен. На 20 юни 35-годишен мъж убива 32-годишната жена, с която живее, оставя 4-годишната ѝ дъщеричка сама насред града, след което се самоубива. Същия ден Орлин Гигов, бивш шофьор в болницата на МВР, убива жената, с която съжителства и която е с украински произход.
Кой е Орлин Гигов
Случаят с Орлин Гигов заслужава специално внимание, защото е впечатляващ пример за институционалното безхаберие по отношение на домашното насилие в България.
Името на Гигов влиза в медиите преди година и половина. През януари 2023-та той се барикадира в дома си, след като изхвърля на стълбите украинската си приятелка Силвия – обезобразена от бой, гола и боса. След като съседи подават сигнал, полицията преговаря с барикадиралия се насилник в продължение на 5 часа. Приятелски и (след като той излиза от апартамента) с потупване по рамото. Бившият шофьор от МВР обяснява на полицаите, че те са му колеги, а Силвия е чужденка – „от друго стадо“.
Повече от денонощие МВР не публикува информация за жертвата. Първоначално от Вътрешното министерство твърдят, че няма пострадали. След като историята се разчува, казват, че не знаят къде е жената.
По информация на OFFNews жените, пострадали от Гигов, са поне пет, а само за три години прокуратурата е получила десет сигнала срещу него. Две от жертвите му разказват пред изданието на какво ги е подлагал и как ги е заплашвал. Например с думите „спокойно, знам как да бия, така че да не личи“, „ще те вкарам в гипсово корито и ще те лежа“, „с този нож ще те разфасовам“. Дъщерята на друга жертва на Гигов споделя, че той не само е пребил и намушкал с нож по краката майка ѝ, която е с увреждане, а е взел и личната карта, телефона и портфейла ѝ. На всичко отгоре се опитал да изтегли бърз кредит от нейно име.
Въпреки цялата налична информация за насилническото поведение на Гигов и данните за извършени от него престъпления (нанасяне на телесна повреда в условията на домашно насилие, кражба и шофиране след употреба на наркотици) институциите не защитават Силвия от него. През юли 2023 г. той пак я пребива – този път в центъра на София. Тя отказва да даде показания и макар че побоят е пред множество свидетели, пак не получава защита.
Скоро след това – в началото на август 2023 г. – парламентът приема промени в Закона за защита от домашното насилие (ЗЗДН), които трябва да гарантират още по-голяма защита на потенциалните жертви. Но и това не помага на Силвия – накрая Орлин Гигов я убива.
Две истории през двайсетина години
Смъртта на Силвия, която можеше да бъде избегната, ако ЗЗДН се прилагаше адекватно, е зловещо напомняне на нещо простичко, но много важно: не е достатъчно да има закони, те трябва да се прилагат. А институциите, ангажирани с прилагането им, трябва да действат отговорно и компетентно.
През близо двайсетте години, откакто е в сила, ЗЗДН има участта системно да се пренебрегва – предимно от представители на МВР. А те първи срещат преживелите домашно насилие, които имат смелост да потърсят защита. И тяхната реакция е от животоспасяващо значение.
Да я наречем Ирина. Ирина е висококвалифицирана специалистка и живее в областен град. Преди двайсетина години се развежда с мъжа си заради непрестанните му пиянски побои. Той обаче не престава да я тормози и след развода. Въпреки че подава сигнали, институциите не ѝ осигуряват защита. Един ден, скоро след като през 2005 г. е приет ЗЗДН, бившият съпруг на Ирина чупи прозореца на жилището ѝ, влиза през него и я пребива. Пред сина им, който е малък, но вече достатъчно голям, за да разбира какво се случва.
Ирина подава в полицията молба за защита от домашно насилие. Оттам я отпращат с аргумента, че в нейния случай преживяното насилие не е домашно, защото извършителят ѝ е бивш, а не настоящ съпруг. Въпреки че и тогавашната формулировка на закона би трябвало да ѝ гарантира защита поне по два признака – тя включва както бившите съпрузи, така и лицата, от които пострадалите имат дете.
През 2024 г. ЗЗДН е в сила от близо две десетилетия, България отдавна е в ЕС и се предполага, че представителите на органите на реда имат достатъчно информация кое е домашно насилие и как да реагират, когато получат сигнал. Да, ама не, както казваше покойният журналист Петко Бочаров.
Само ден преди убийствата на две жени, на 20 юни, съпредседателят на БХК Радослав Стоянов се обръща към министъра на МВР с открито писмо. Поводът е реакцията на служители от Второ РПУ в София спрямо случай на жена, чийто партньор, с когото тя живее, ѝ е причинил телесна повреда. Той е задържан за кратко, след което е освободен, а на нея полицейските служители всячески пречат да получи защита.
Стоянов се заема със случая лично и се опитва да обясни на представителите на полицията, че жената е пострадала от домашно насилие и съответно има право на защита по силата на ЗЗДН. Според тях обаче правозащитникът греши: щом насилието не било извършено „в домашна среда“, значи не е домашно насилие, и точка. Въпреки че според закона домашното насилие се определя не от мястото на извършването му, а от характера на връзката между извършителите и пострадалите.
Защо обучението на полицаи не е достатъчно
Ако служителите на МВР системно не осигуряват защита на жертвите от домашно насилие, логично е да си помислим, че трябва да се научат да го правят. А класическият начин за научаване е чрез обучение. Само в рамките на един проект обаче, представен през април т.г., 830 полицаи са обучавани как да гарантират защита от домашно насилие. Резултатът е още неадекватни реакции, още незащитени жертви и още убийства.
Ако човек научаваше всичко, на което се обучава, образованието щеше да бъде далеч по-ефективно. Но, уви – при ученето има поне два сериозни проблема. Първият е, че не всичко, което влиза в главата, остава в нея. Вторият – и по-сериозен – проблем е, че ако човек назубри нещо, това не означава, че е в състояние да го прилага.
Между обучителният материал и приложението му стои не само наличието или липсата на внимание. Намесват се ценности, стереотипи, авторитети, модели на мислене и на поведение, личен опит, индивидуални особености и какво ли още не.
Ако служителите на реда са възпитавани в патриархална среда, имат мачистки ценности и намират утвърждение на ценностния си модел в публичното пространство и в политическите послания, само с обучение няма да стане. Те могат да си назубрят материала, както се зубри в училище, и пак да правят каквото си знаят. Ако за тях мъжката и гилдийната лоялност е по-важна от законите, ще потупват по рамото и ще наричат колега поредния Орлин Гигов, докато не се стигне до поредното убийство.
Промяна в обществените настроения настъпи след случая с обезобразената и нарязана с макетно ножче Дебора Михайлова. Но още е рано да се каже дали кампанийният гняв, довел тогава до промени в ЗЗДН, може да израсне от популизъм до осъзната чувствителност към проблема с домашното насилие.
Неслучилото се българско #metoo
Чувствителност към насилието над жени и към домашното насилие в едно общество има тогава, когато то не се възмущава от отделни случаи, оставайки сляпо за други, а осъзнава системния проблем. И не се влияе от симпатии, антипатии, авторитети или популярност. В България не изглежда да е така. Докато Дебора спечели обществените симпатии, украинката Силвия и много жени в нейното положение нямаха този шанс.
Показателно е, че в България няма #metoo. Като имаме предвид, че между 1/4 и 1/3 от жените в България са преживели насилие от страна на настоящ или бивш партньор, е малко вероятно да няма популярни актриси, музикантки и други жени от шоубизнеса, които са били обект на насилие, нито популярни мъже, които да са извършвали такива действия. Ала темата продължава да е табу.
Досега единствено актрисата Диана Димитрова заяви, че колегата ѝ Юлиан Вергов я е бил. Въпреки че трийсетина души от снимачния екип на сериала „Откраднат живот“ могат да потвърдят какво се е случило, това прави само гримьорката, прикрила следите от побоя, за да продължат снимките. И по-късно – няколко представители на техническия персонал, които не са присъствали в съответния ден, но споделят какво се е говорило в екипа.
Представителите на актьорската гилдия обаче или застават на страната на Вергов, обвинявайки Димитрова във всевъзможни грехове (хем че лъже, хем че „си го е търсела“), или си мълчат. Тя получава подкрепа комай само от актрисите Весела Казакова и Елен Колева.
Днес Вергов е целият в бяло, а Димитрова напуска актьорската професия, може би и България, и ще учи анимация. След скандала тя се занимава все повече с рисуване и все по-малко с актьорство. Което е обяснимо – след като дори хората, с които работиш, не казват и една дума в твоя подкрепа, колко дълго можеш да продължиш да го правиш?
Нови политически сезони – старо безразличие
Докато не се знае дали изобщо ще има правителство, темата за домашното насилие ще е последният проблем на партиите и коалициите. Вероятно няма да е особено съществен проблем и след това, стига да няма пореден случай като този с Дебора, който да разпали обществените страсти. И да се стигне до поредни недообмислени промени на ЗЗДН, с който полицейските служители така и така не се съобразяват.
Насилието над жени и домашното насилие са от тези теми, на които почти никога не им е времето, защото има по-важни неща за решаване. С такива проблеми се занимават развитите демокрации. Но докато чакаме България „да се оправи“ и да стане като развитите демокрации, не само редовно биват пребивани и убивани жени. По-голямата беда дори от това е, че слагаме каруцата пред коня. Не може първо да си оправим държавата, после – проблемите с ценностите и нагласите. Напротив – когато изповядваме демократични ценности, част от които е неприемането на домашното насилие, и действаме спрямо тях, тогава може и да станем развита демокрация.
In November 2020, we introduced the concept of prioritized load shedding at the API gateway level in our blog post, Keeping Netflix Reliable Using Prioritized Load Shedding. Today, we’re excited to dive deeper into how we’ve extended this strategy to the individual service level, focusing on the video streaming control plane and data plane, to further enhance user experience and system resilience.
The Evolution of Load Shedding at Netflix
At Netflix, ensuring a seamless viewing experience for millions of users simultaneously is paramount. Our initial approach for prioritized load shedding was implemented at the Zuul API gateway layer. This system effectively manages different types of network traffic, ensuring that critical playback requests receive priority over less critical telemetry traffic.
Building on this foundation, we recognized the need to apply a similar prioritization logic deeper within our architecture, specifically at the service layer where different types of requests within the same service could be prioritized differently. The advantages of applying these techniques at the service level in addition to our edge API gateway are:
Service teams can own their prioritization logic and can apply finer grained prioritization.
This can be used for backend to backend communication, i.e. for services not sitting behind our edge API gateway.
Services can use cloud capacity more efficiently by combining different request types into one cluster and shedding low priority requests when necessary instead of maintaining separate clusters for failure isolation.
PlayAPI is a critical backend service on the video streaming control plane, responsible for handling device initiated manifest and license requests necessary to start playback. We categorize these requests into two types based on their criticality:
User-Initiated Requests (critical): These requests are made when a user hits play and directly impact the user’s ability to start watching a show or a movie.
Pre-fetch Requests (non-critical): These requests are made optimistically when a user browses content without the user hitting play, to reduce latency should the user decide to watch a particular title. A failure in only pre-fetch requests does not result in a playback failure, but slightly increases the latency between pressing play and video appearing on screen.
Netflix on Chrome making pre-fetch requests to PlayAPI while the user is browsing content
The Problem
In order to handle large traffic spikes, high backend latency, or an under-scaled backend service, PlayAPI previously used a concurrency limiter to throttle requests that would reduce the availability of both user-initiated and prefetch requests equally. This was not ideal because:
Spikes in pre-fetch traffic reduced availability for user-initiated requests
Increased backend latency reduced availability for user-initiated requests and pre-fetch requests equally, when the system had enough capacity to serve all user-initiated requests.
Sharding the critical and non-critical requests into separate clusters was an option, which addressed problem 1 and added failure isolation between the two types of requests, however it came with a higher compute cost. Another disadvantage of sharding is that it adds some operational overhead — engineers need to make sure CI/CD, auto-scaling, metrics, and alerts are enabled for the new cluster.
Option 1 — No isolationOption 2 — Isolation but higher compute cost
Our Solution
We implemented a concurrency limiter within PlayAPI that prioritizes user-initiated requests over prefetch requests without physically sharding the two request handlers. This mechanism uses the partitioning functionality of the open source Netflix/concurrency-limits Java library. We create two partitions in our limiter:
Pre-fetch Partition: Utilizes only excess capacity.
Option 3 — Single cluster with prioritized load-shedding offers application-level isolation with lower compute cost. Each instance serves both types of requests and has a partition whose size adjusts dynamically to ensure that pre-fetch requests only get excess capacity. This allows user-initiated requests to “steal” pre-fetch capacity when necessary.
The partitioned limiter is configured as a pre-processing Servlet Filter that uses HTTP headers sent by devices to determine a request’s criticality, thus avoiding the need to read and parse the request body for rejected requests. This ensures that the limiter is not itself a bottleneck and can effectively reject requests while using minimal CPU. As an example, the filter can be initialized as
Filter filter = new ConcurrencyLimitServletFilter(
        new ServletLimiterBuilder()
                .named("playapi")
                .partitionByHeader("X-Netflix.Request-Name")
                .partition("user-initiated", 1.0)
                .partition("pre-fetch", 0.0)
                .build());
Note that in steady state, there is no throttling and the prioritization has no effect on the handling of pre-fetch requests. The prioritization mechanism only kicks in when a server is at the concurrency limit and needs to reject requests.
Testing
In order to validate that our load-shedding worked as intended, we used Failure Injection Testing to inject 2 second latency in pre-fetch calls, where the typical p99 latency for these calls is < 200 ms. The failure was injected on one baseline instance with regular load shedding and one canary instance with prioritized load shedding. Some internal services that PlayAPI calls use separate clusters for user-initiated and pre-fetch requests and run pre-fetch clusters hotter. This test case simulates a scenario where a pre-fetch cluster for a downstream service is experiencing high latency.
Baseline — Without prioritized load-shedding. Both pre-fetch and user-initiated see an equal drop in availabilityCanary — With prioritized load-shedding. Only pre-fetch availability drops while user-initiated availability stays at 100%
Without prioritized load-shedding, both user-initiated and prefetch availability drop when latency is injected. However, after adding prioritized load-shedding, user-initiated requests maintain a 100% availability and only prefetch requests are throttled.
We were ready to roll this out to production and see how it performed in the wild!
Real-World Application and Results
Netflix engineers work hard to keep our systems available, and it was a while before we had a production incident that tested the efficacy of our solution. A few months after deploying prioritized load shedding, we had an infrastructure outage at Netflix that impacted streaming for many of our users. Once the outage was fixed, we got a 12x spike in pre-fetch requests per second from Android devices, presumably because there was a backlog of queued requests built up.
Spike in Android pre-fetch RPS
This could have resulted in a second outage as our systems weren’t scaled to handle this traffic spike. Did prioritized load-shedding in PlayAPI help us here?
Yes! While the availability for prefetch requests dropped as low as 20%, the availability for user-initiated requests was > 99.4% due to prioritized load-shedding.
Availability of pre-fetch and user-initiated requests
At one point we were throttling more than 50% of all requests but the availability of user-initiated requests continued to be > 99.4%.
Generic service work prioritization
Based on the success of this approach, we have created an internal library to enable services to perform prioritized load shedding based on pluggable utilization measures, with multiple priority levels.
Unlike API gateway, which needs to handle a large volume of requests with varying priorities, most microservices typically receive requests with only a few distinct priorities. To maintain consistency across different services, we have introduced four predefined priority buckets inspired by the Linux tc-prio levels:
CRITICAL: Affect core functionality — These will never be shed if we are not in complete failure.
DEGRADED: Affect user experience — These will be progressively shed as the load increases.
BEST_EFFORT: Do not affect the user — These will be responded to in a best effort fashion and may be shed progressively in normal operation.
BULK: Background work, expect these to be routinely shed.
Services can either choose the upstream client’s priority or map incoming requests to one of these priority buckets by examining various request attributes, such as HTTP headers or the request body, for more precise control. Here is an example of how services can map requests to priority buckets:
Most services at Netflix autoscale on CPU utilization, so it is a natural measure of system load to tie into the prioritized load shedding framework. Once a request is mapped to a priority bucket, services can determine when to shed traffic from a particular bucket based on CPU utilization. In order to maintain the signal to autoscaling that scaling is needed, prioritized shedding only starts shedding load after hitting the target CPU utilization, and as system load increases, more critical traffic is progressively shed in an attempt to maintain user experience.
For example, if a cluster targets a 60% CPU utilization for auto-scaling, it can be configured to start shedding requests when the CPU utilization exceeds this threshold. When a traffic spike causes the cluster’s CPU utilization to significantly surpass this threshold, it will gradually shed low-priority traffic to conserve resources for high-priority traffic. This approach also allows more time for auto-scaling to add additional instances to the cluster. Once more instances are added, CPU utilization will decrease, and low-priority traffic will resume being served normally.
Percentage of requests (Y-axis) being load-shed based on CPU utilization (X-axis) for different priority buckets
Experiments with CPU based load-shedding
We ran a series of experiments sending a large request volume at a service which normally targets 45% CPU for auto scaling but which was prevented from scaling up for the purpose of monitoring CPU load shedding under extreme load conditions. The instances were configured to shed noncritical traffic after 60% CPU and critical traffic after 80%.
As RPS was dialed up past 6x the autoscale volume, the service was able to shed first noncritical and then critical requests. Latency remained within reasonable limits throughout, and successful RPS throughput remained stable.
Experimental behavior of CPU based load-shedding using synthetic traffic.P99 latency stayed within a reasonable range throughout the experiment, even as RPS surpassed 6x the autoscale target.
Anti-patterns with load-shedding
Anti-pattern 1 — No shedding
In the above graphs, the limiter does a good job keeping latency low for the successful requests. If there was no shedding here, we’d see latency increase for all requests, instead of a fast failure in some requests that can be retried. Further, this can result in a death spiral where one instance becomes unhealthy, resulting in more load on other instances, resulting in all instances becoming unhealthy before auto-scaling can kick in.
No load-shedding: In the absence of load-shedding, increased latency can degrade all requests instead of rejecting some requests (that can be retried), and can make instances unhealthy
Anti-pattern 2 — Congestive failure
Another anti-pattern to watch out for is congestive failure or shedding too aggressively. If the load-shedding is due to an increase in traffic, the successful RPS should not drop after load-shedding. Here is an example of what congestive failure looks like:
Congestive failure: After 16:57, the service starts rejecting most requests and is not able to sustain a successful 240 RPS that it was before load-shedding kicked in. This can be seen in fixed concurrency limiters or when load-shedding consumes too much CPU preventing any other work from being done
We can see in the Experiments with CPU based load-shedding section above that our load-shedding implementation avoids both these anti-patterns by keeping latency low and sustaining as much successful RPS during load-shedding as before.
Generic IO based load-shedding
Some services are not CPU-bound but instead are IO-bound by backing services or datastores that can apply back pressure via increased latency when they are overloaded either in compute or in storage capacity. For these services we re-use the prioritized load shedding techniques, but we introduce new utilization measures to feed into the shedding logic. Our initial implementation supports two forms of latency based shedding in addition to standard adaptive concurrency limiters (themselves a measure of average latency):
The service can specify per-endpoint target and maximum latencies, which allow the service to shed when the service is abnormally slow regardless of backend.
The Netflix storage services running on the Data Gateway return observed storage target and max latency SLO utilization, allowing services to shed when they overload their allocated storage capacity.
These utilization measures provide early warning signs that a service is generating too much load to a backend, and allow it to shed low priority work before it overwhelms that backend. The main advantage of these techniques over concurrency limits alone is they require less tuning as our services already must maintain tight latency service-level-objectives (SLOs), for example a p50 < 10ms and p100 < 500ms. So, rephrasing these existing SLOs as utilizations allows us to shed low priority work early to prevent further latency impact to high priority work. At the same time, the system will accept as much work as it can while maintaining SLO’s.
To create these utilization measures, we count how many requests are processed slower than our target and maximum latency objectives, and emit the percentage of requests failing to meet those latency goals. For example, our KeyValue storage service offers a 10ms target with 500ms max latency for each namespace, and all clients receive utilization measures per data namespace to feed into their prioritized load shedding. These measures look like:
In this case, 12% of requests are slower than the 10ms target, 0% are slower than the 500ms max latency (timeout), and 17% of allocated storage is utilized. Different use cases consult different utilizations in their prioritized shedding, for example batches that write data daily may get shed when system storage utilization is approaching capacity as writing more data would create further instability.
An example where the latency utilization is useful is for one of our critical file origin services which accepts writes of new files in the AWS cloud and acts as an origin (serves reads) for those files to our Open Connect CDN infrastructure. Writes are the most critical and should never be shed by the service, but when the backing datastore is getting overloaded, it is reasonable to progressively shed reads to files which are less critical to the CDN as it can retry those reads and they do not affect the product experience.
To achieve this goal, the origin service configured a KeyValue latency based limiter that starts shedding reads to files which are less critical to the CDN when the datastore reports a target latency utilization exceeding 40%. We then stress tested the system by generating over 50Gbps of read traffic, some of it to high priority files and some of it to low priority files:
In this test, there are a nominal number of critical writes and a high number of reads to both low and high priority files. In the top-left graph we ramp to 2000 read/second of ~4MiB files until we can trigger overload of the backend store at over 50Gbps in the top-center graph. When that happens, the top-right graph shows that even under significant load, the origin only sheds low priority read work to preserve high-priority writes and reads. Before this change when we hit breaking points, critical writes and reads would fail along with low priority reads. During this test the CPU load of the file serving service was nominal (<10%), so in this case only IO based limiters are able to protect the system. It is also important to note that the origin will serve more traffic as long as the backing datastore continues accepting it with low latency, preventing the problems we had with concurrency limits in the past where they would either shed too early when nothing was actually wrong or too late when we had entered congestive failure.
Conclusion and Future Directions
The implementation of service-level prioritized load shedding has proven to be a significant step forward in maintaining high availability and excellent user experience for Netflix customers, even during unexpected system stress.
Stay tuned for more updates as we innovate to keep your favorite shows streaming smoothly, no matter what SLO busters lie in wait.
Acknowledgements
We would like to acknowledge the many members of the Netflix consumer product, platform, and open connect teams who have designed, implemented, and tested these prioritization techniques. In particular: Xiaomei Liu, Raj Ummadisetty, Shyam Gala, Justin Guerra, William Schor, Tony Ghita et al.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
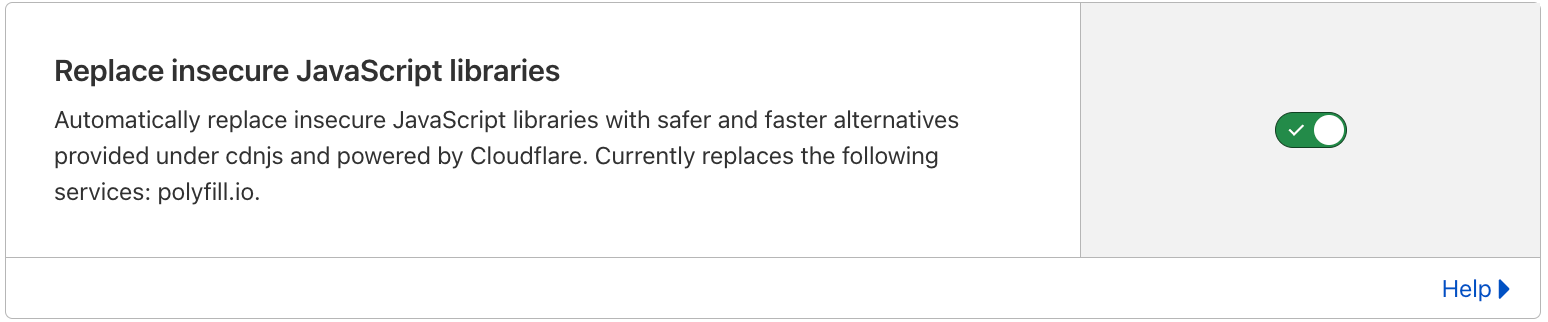


 Anish Anturkar is a Software Engineer and Designer and part of Amazon DataZone with an expertise in distributed software solutions. He is passionate about building robust, scalable, and sustainable software solutions for his customers.
 Navneet Srivastava is a Principal Specialist and Analytics Strategy Leader, and develops strategic plans for building an end-to-end analytical strategy for large biopharma, healthcare, and life sciences organizations. Navneet is responsible for helping life sciences organizations and healthcare companies deploy data governance and analytical applications, electronic medical records, devices, and AI/ML-based applications, while educating customers about how to build secure, scalable, and cost-effective AWS solutions. His expertise spans across data analytics, data governance, AI, ML, big data, and healthcare-related technologies.
 Priya Tiruthani is a Senior Technical Product Manager with Amazon DataZone at AWS. She focuses on improving data discovery and curation required for data analytics. She is passionate about building innovative products to simplify customers’ end-to-end data journey, especially around data governance and analytics. Outside of work, she enjoys being outdoors to hike, capture nature’s beauty, and recently play pickleball.
 Subrat Das is a Senior Solutions Architect and part of the Global Healthcare and Life Sciences industry division at AWS. He is passionate about modernizing and architecting complex customer workloads. When he’s not working on technology solutions, he enjoys long hikes and traveling around the world.