Embedded function calling in Workers AI: easier, smarter, faster

Post Syndicated from Harley Turan original https://blog.cloudflare.com/embedded-function-calling

Introducing embedded function calling and a new ai-utils package

Today, we’re excited to announce a novel way to do function calling that co-locates LLM inference with function execution, and a new ai-utils package that upgrades the developer experience for function calling.

This is a follow-up to our mid-June announcement for traditional function calling, which allows you to leverage a Large Language Model (LLM) to intelligently generate structured outputs and pass them to an API call. Function calling has been largely adopted and standardized in the industry as a way for AI models to help perform actions on behalf of a user.

Our goal is to make building with AI as easy as possible, which is why we’re introducing a new @cloudflare/ai-utils npm package that allows developers to get started quickly with embedded function calling. These helper tools drastically simplify your workflow by actually executing your function code and dynamically generating tools from OpenAPI specs. We’ve also open-sourced our ai-utils package, which you can find on GitHub. With both embedded function calling and our ai-utils, you’re one step closer to creating intelligent AI agents, and from there, the possibilities are endless.

Why Cloudflare’s AI platform?

OpenAI has been the gold standard when it comes to having performant model inference and a great developer experience. However, they mostly support their closed-source models, while we want to also promote the open-source ecosystem of models. One of our goals with Workers AI is to match the developer experience you might get from OpenAI, but with open-source models.

There are other open-source inference providers out there like Azure or Bedrock, but most of them are focused on serving inference and the underlying infrastructure, rather than being a developer toolkit. While there are external libraries and frameworks like AI SDK that help developers build quickly with simple abstractions, they rely on upstream providers to do the actual inference. With Workers AI, it’s the best of both worlds – we offer open-source model inference and a killer developer experience out of the box.

With the release of embedded function calling and ai-utils today, we’ve advanced how we do inference for function calling and improved the developer experience by making it dead simple for developers to start building AI experiences.

How does traditional function calling work?

Traditional LLM function calling allows customers to specify a set of function names and required arguments along with a prompt when running inference on an LLM. The LLM returns the names and arguments for the functions that the customer can then make to perform actions. These actions give LLMs the ability to do things like fetch fresh data not present in the training dataset and “perform actions” based on user intent.
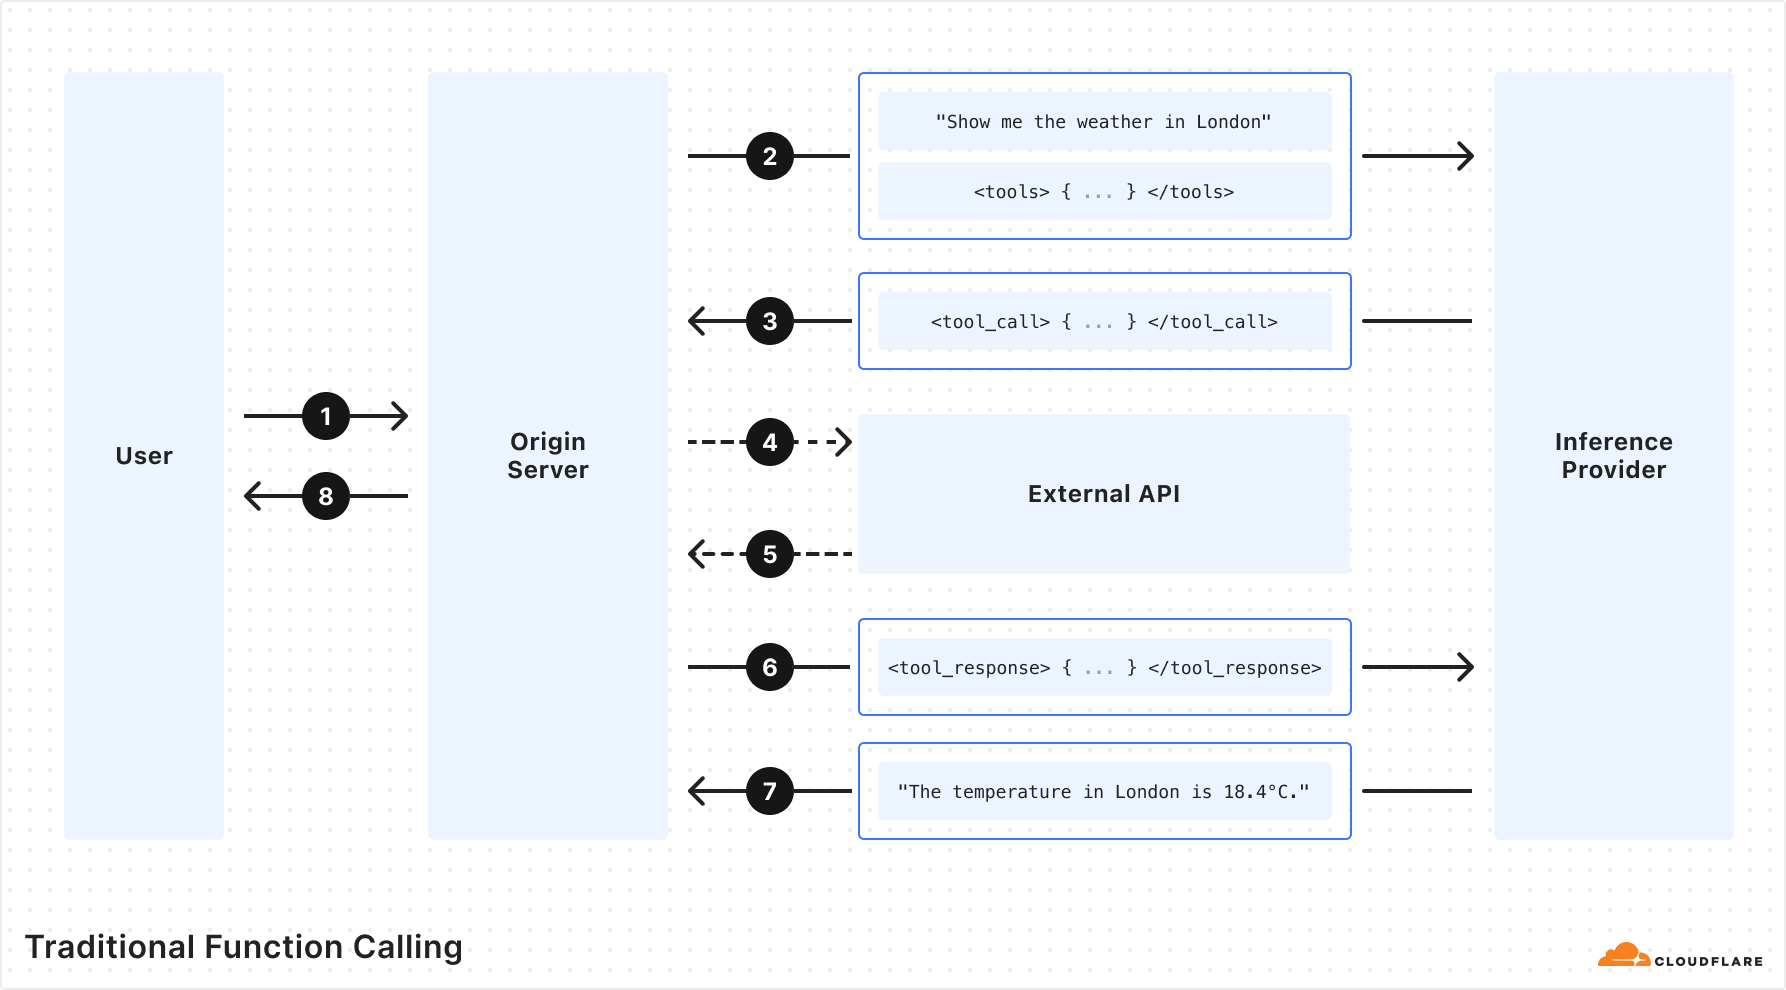
Traditional function calling requires multiple back-and-forth requests passing through the network in order to get to the final output. This includes requests to your origin server, an inference provider, and external APIs. As a developer, you have to orchestrate all the back-and-forths and handle all the requests and responses. If you were building complex agents with multi-tool calls or recursive tool calls, it gets infinitely harder. Fortunately, this doesn’t have to be the case, and we’ve solved it for you.

Embedded function calling

With Workers AI, our inference runtime is the Workers platform, and the Workers platform can be seen as a global compute network of distributed functions (RPCs). With this model, we can run inference using Workers AI, and supply not only the function names and arguments, but also the runtime function code to be executed. Rather than performing multiple round-trips across networks, the LLM inference and function can run in the same execution environment, cutting out all the unnecessary requests.
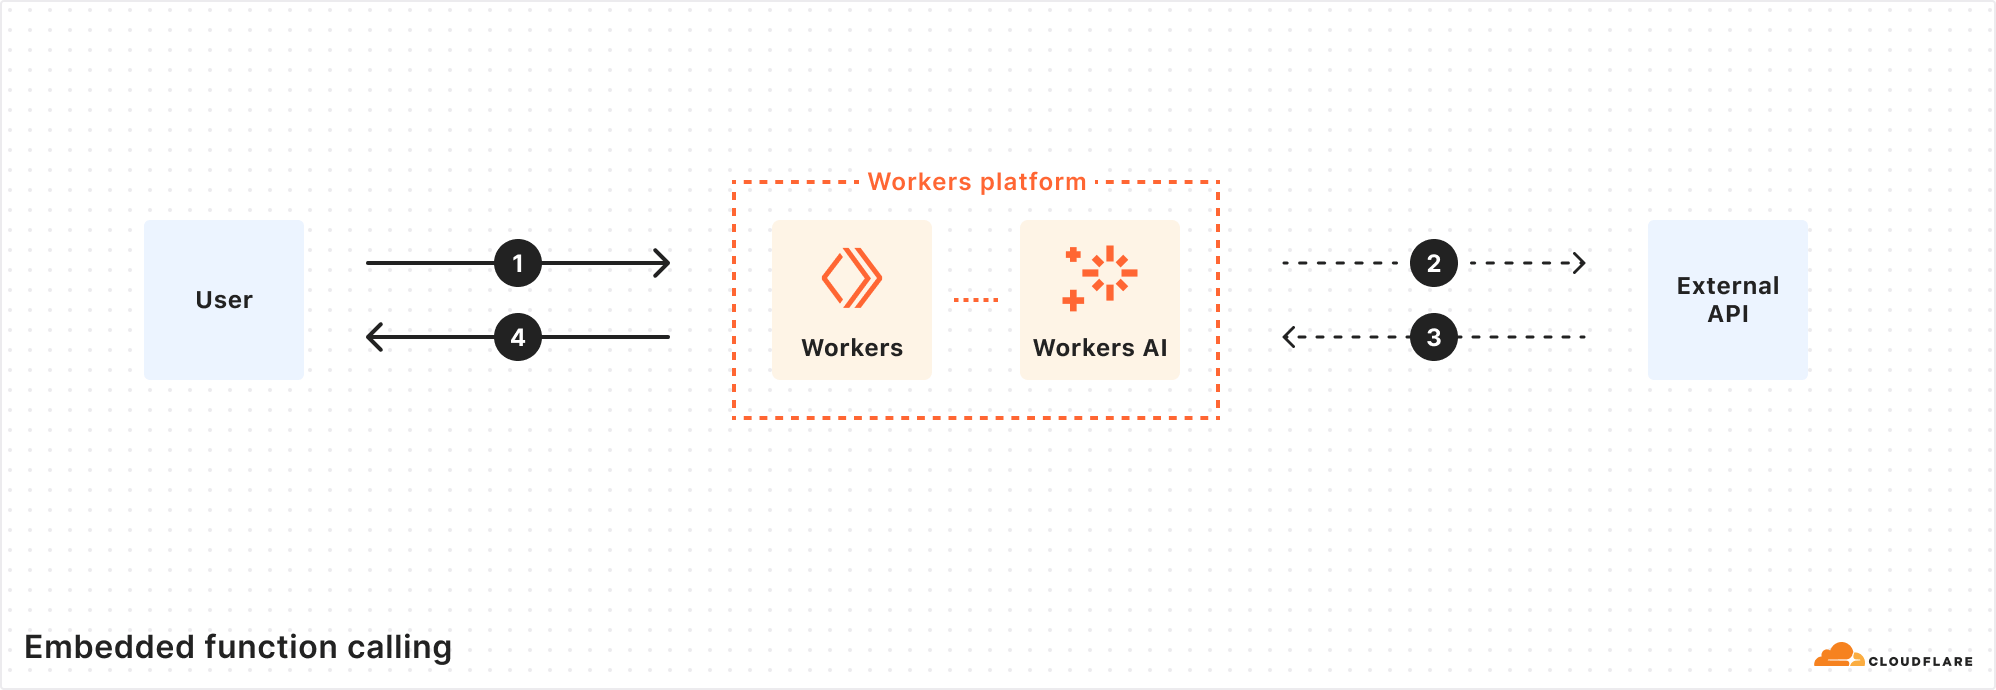
Cloudflare is one of the few inference providers that is able to do this because we offer more than just inference – our developer platform has compute, storage, inference, and more, all within the same Workers runtime.

We made it easy for you with a new ai-utils package

And to make it as simple as possible, we created a @cloudflare/ai-utils package that you can use to get started. These powerful abstractions cut down on the logic you have to implement to do function calling – it just works out of the box.

runWithTools

runWithTools is our method that you use to do embedded function calling. You pass in your AI binding (env.AI), model, prompt messages, and tools. The tools array includes the description of the function, similar to traditional function calling, but you also pass in the function code that needs to be executed. This method makes the inference calls and executes the function code in one single step. runWithTools is also able to handle multiple function calls, recursive tool calls, validation for model responses, streaming for the final response, and other features.

Another feature to call out is a helper method called autoTrimTools that automatically selects the relevant tools and trims the tools array based on the names and descriptions. We do this by adding an initial LLM inference call to intelligently trim the tools array before the actual function-calling inference call is made. We found that autoTrimTools helped decrease the number of total tokens used in the entire process (especially when there’s a large number of tools provided) because there’s significantly fewer input tokens used when generating the arguments list. You can choose to use autoTrimTools by setting it as a parameter in the runWithTools method.

const response = await runWithTools(env.AI,"@hf/nousresearch/hermes-2-pro-mistral-7b",
  {
    messages: [{ role: "user", content: "What's the weather in Austin, Texas?"}],
    tools: [
      {
        name: "getWeather",
        description: "Return the weather for a latitude and longitude",
        parameters: {
          type: "object",
          properties: {
            latitude: {
              type: "string",
              description: "The latitude for the given location"
            },
            longitude: {
              type: "string",
              description: "The longitude for the given location"
            }
          },
          required: ["latitude", "longitude"]
        },
	 // function code to be executed after tool call
        function: async ({ latitude, longitude }) => {
          const url = `https://api.weatherapi.com/v1/current.json?key=${env.WEATHERAPI_TOKEN}&q=${latitude},${longitude}`
          const res = await fetch(url).then((res) => res.json())

          return JSON.stringify(res)
        }
      }
    ]
  },
  {
    streamFinalResponse: true,
    maxRecursiveToolRuns: 5,
    trimFunction: autoTrimTools,
    verbose: true,
    strictValidation: true
  }
)

createToolsFromOpenAPISpec

For many use cases, users will need to make a request to an external API call during function calling to get the output needed. Instead of having to hardcode the exact API endpoints in your tools array, we made a helper function that takes in an OpenAPI spec and dynamically generates the corresponding tool schemas and API endpoints you’ll need for the function call. You call createToolsFromOpenAPISpec from within runWithTools and it’ll dynamically populate everything for you.

const response = await runWithTools(env.AI, "@hf/nousresearch/hermes-2-pro-mistral-7b", {
  messages: [{ role: "user",content: "Can you name me 5 repos created by Cloudflare"}],
  tools: [
    ...(await createToolsFromOpenAPISpec(  "https://raw.githubusercontent.com/github/rest-api-description/main/descriptions-next/api.github.com/api.github.com.json"
    ))
  ]
})

Putting it all together

When you make a function calling inference request with runWithTools and createToolsFromOpenAPISpec, the only thing you need is the prompts – the rest is automatically handled. The LLM will choose the correct tool based on the prompt, the runtime will execute the function needed, and you’ll get a fast, intelligent response from the model. By leveraging our Workers runtime’s bindings and RPC calls along with our global network, we can execute everything from a single location close to the user, enabling developers to easily write complex agentic chains with fewer lines of code.

We’re super excited to help people build intelligent AI systems with our new embedded function calling and powerful tools. Check out our developer docs on how to get started, and let us know what you think on Discord.

MikroTik CRS520-4XS-16XQ-RM 16-port 100GbE Switch Announced

Post Syndicated from Rohit Kumar original https://www.servethehome.com/mikrotik-crs520-4xs-16xq-rm-16-port-100gbe-switch-announced-marvell-arm-annapurna-labs/

The upcoming MikroTik CRS520-4XS-16XQ-RM is a 16-port 100GbE switch based on a new Marvell switch chip for under $2800 new

The post MikroTik CRS520-4XS-16XQ-RM 16-port 100GbE Switch Announced appeared first on ServeTheHome.

Вниманието

Post Syndicated from Тоест original https://www.toest.bg/vnimanieto/

Вниманието

е бяло стъклено топче, прозрачно, с тюркоазена ивица –
плиснала вътре вълна; то е топче, подскачащо бясно надолу по уличката
       до бара на стълбите, дето с тебе се срещахме в Монти,
Мартино, да седим цяла вечер и да пием на стълбите, всяко стъпало
       бе вдлъбнато по средата от безчетни крака на поклонници, тръгнали
към Сан Пиетро ин Винколи, прошка да търсят, да склонят глави, да отправят
       въпроси към себе си там, където вниманието е блок монолитен
карарски бял мрамор, издялан от Микеланджело в статуя на Мойсей,
       пред която стояхме напушени и се чудехме защо е с рога, вниманието
към стила на нещата, Мартино, е нещо, което ти носиш из Хокстън
       или Тестачо като лилав гащеризон, какъвто и носеше,
вниманието е бяло стъклено топче, което сега слиза по каменните
       стълби пред бара, търкулва се първо в една, после в друга
вдлъбнатина на стъпало, търкулва се, пада надолу, търкулва се,
       пада, търкулва се, пада, не тихо, додето накрая бялото
топче, прозрачно, с тюркоазена ивица, удря бордюра и спира
       на паважа, досущ като перла, под гумата на една веспа.
Мартино, в Лондон е вечер, вали, правя чай и не си го казваме,
       но и двамата знаем: това е последният път. Лицето ти
е подуто от тази терапия, главата ти фантастично съшита,
       ти седиш на ръба на дивана, цял внимание, цял окован във вериги
от внимание. I vincoli – спойки, връзки, задръжки, окови. Също
       задължения, граници. На свети Петър, църковния камък, оковите
са в ковчеже от бял седеф, Фройд го подминал на път към Мойсей,
       според него седящ, лицето му гледа напред, главата с могъща
брада гледа наляво, десният крак е стъпил, а левият вдигнат,

       тъй че само пръстите докосват земята. На мен това ми говори,
че Мойсей едва се удържа, че вече почти не смогва,
       че а-ха ще стане и нещо страхотно ще рукне – гняв,
според мен отприщен – и че раздразнен гледа туристите долу,
       докато отвърнат очи, както Фройд, който идвал всеки следобед
в стремеж да прозре ефекта на статуята. Внимание, на латински
       от глагола ad tendere, да се протегнеш към нещо; в главата ти, Тино,
туморът толкова бързо расте, че сега е във форма на птиче, на сипка
       сред полет, изкълвала ума ти дотам, че още можеш да пишеш,
но не да четеш, и додето седиш при мен в кухнята и внимаваш, цял окован
       във вериги от бяло внимание, цял зареден с беззащитно, ужасно
внимание, как горя да ти кажа, че Микеланджело толкова много обичал
       тази статуя, че запратил чука си по нея и плакал, задето мълчи.

Ник Леърд
Превод от английски Ангел Игов


Ник Леърд (р. 1975) е поет, романист, сценарист, критик, автор на детски книги и бивш адвокат, роден в Дънганън в Северна Ирландия. Носител на наградите „Бети Траск“, „Руни“, „Джофри Фейбър Мемориъл“, „Форуърд“, „Съмърсет Моъм“ и на стипендията „Гугенхайм“. Преподавал е в американски университети като Принстънския, Колумбийския и Нюйоркския , а в момента държи почетната професура по поезия на името на Шеймъс Хийни в Университета „Куинс“ в Белфаст. Публикуваното стихотворение е преведено в рамките на Международната поетическа конференция, организирана от Фондация „Елизабет Костова“ в Копривщица през юни 2024 г.

Ангел Игов (р. 1981) е писател, критик, преводач и доцент по английска литература и превод в Софийския университет. Носител на наградата „Христо Г. Данов“ за романа „Кротките“ и на наградата „Кръстан Дянков“ за преводите на „Колекционерът на изгубени неща“ от Джеръми Пейдж и на „Подземната железница“ от Колсън Уайтхед. В момента работи върху превода на избрани стихотворения от Шеймъс Хийни.


Според Екатерина Йосифова „четящият стихотворение сутрин… добре понася другите часове“ от деня. Убедени, че поезията държи умовете ни будни, а сърцата – отворени, в края на всеки месец ви предлагаме по едно стихотворение. Защото и в най-смутни времена доброто стихотворение е добра новина.

Access AWS services programmatically using trusted identity propagation

Post Syndicated from Roberto Migli original https://aws.amazon.com/blogs/security/access-aws-services-programmatically-using-trusted-identity-propagation/

With the introduction of trusted identity propagation, applications can now propagate a user’s workforce identity from their identity provider (IdP) to applications running in Amazon Web Services (AWS) and to storage services backing those applications, such as Amazon Simple Storage Service (Amazon S3) or AWS Glue. Since access to applications and data can now be granted directly to a workforce identity, a seamless single sign-on experience can be achieved, eliminating the need for users to be aware of different AWS Identity and Access Management (IAM) roles to assume to access data or use of local database credentials.

While AWS managed applications such as Amazon QuickSight, AWS Lake Formation, or Amazon EMR Studio offer a native setup experience with trusted identity propagation, there are use cases where custom integrations must be built. You might want to integrate your workforce identities into custom applications storing data in Amazon S3 or build an interface on top of existing applications using Java Database Connectivity (JDBC) drivers, allowing these applications to propagate those identities into AWS to access resources on behalf of their users. AWS resource owners can manage authorization directly in their AWS applications such as Lake Formation or Amazon S3 Access Grants.

This blog post introduces a sample command-line interface (CLI) application that enables users to access AWS services using their workforce identity from IdPs such as Okta or Microsoft Entra ID.

The solution relies on users authenticating with their chosen IdP using standard OAuth 2.0 authentication flows to receive an identity token. This token can then be exchanged against AWS Security Token Service (AWS STS) and AWS IAM Identity Center to access data on behalf of the workforce identity that was used to sign in to the IdP.

Finally, an integration with the AWS Command Line Interface (AWS CLI) is provided, enabling native access to AWS services on behalf of the signed-in identity.

In this post, you will learn how to build and use the CLI application to access data on S3 Access Grants, query Amazon Athena tables, and programmatically interact with other AWS services that support trusted identity propagation.

To set up the solution in this blog post, you should already be familiar with trusted identity propagation and S3 Access Grants concepts and features. If you are not, see the two-part blog post How to develop a user-facing data application with IAM Identity Center and S3 Access Grants (Part 1) and Part 2. In this post we guide you through a more hands-on setup of your own sample CLI application.

Architecture and token exchange flow

Before moving into the actual deployment, let’s talk about the architecture of the CLI and how it facilitates token exchange between different parties.

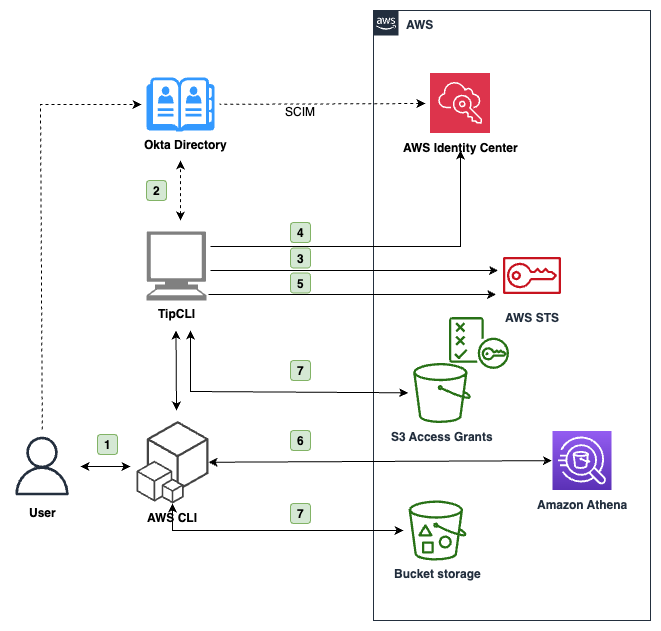
Users, such as developers and data scientists, run the CLI on their machine without AWS security credentials pre-configured. To perform a token exchange of the OAuth 2.0 credentials vended by a source IdP towards IAM Identity Center by using the CreateTokenWithIAM API, AWS security credentials are required. To fulfill this requirement, the solution uses IAM OpenID Connect (OIDC) federation to first create an IAM role session using the AssumeRoleWithWebIdentity API with the initial IdP token—because this API doesn’t require credentials—and then uses the resulting IAM role to request the necessary single sign-on OIDC token.

The process flow is shown in Figure 1:

Figure 1: Architecture diagram of the application

Figure 1: Architecture diagram of the application

At a high level, the interaction flow shown in Figure 1 is the following:

  1. The user interacts with the AWS CLI, which uses the CLI as a source credential provider.
  2. The user is asked to sign in through their browser with the source IdP they configured in the CLI, for example Okta.
  3. If the authorization is successful, the CLI receives a JSON Web Token (JWT) and uses it to assume an IAM role through OIDC federation using AssumeRoleWithWebIdentity.
  4. With this temporary IAM role session, the CLI exchanges the IdP token token with the IAM Identity Center customer managed application on behalf of the user for another token using the CreateTokenWithIAM API.
  5. If successful, the CLI uses the token returned from Identity Center to create an identity-enhanced IAM role session and returns the corresponding IAM credentials to the AWS CLI.
  6. The AWS CLI uses the credentials to call AWS services that support the trusted identity propagation that has been configured in the Identity Center customer managed application. For example, to query Athena. See Specify trusted applications in the Identity Center documentation to learn more.
  7. If you need access to S3 Access Grants, the CLI also provides automatic credentials requests to S3 GetDataAccess with the identity-enhanced IAM role session previously created.

Because both the Okta OAuth token and the identity-enhanced IAM role session credentials are short lived, the CLI provides functionality to refresh authentication automatically.

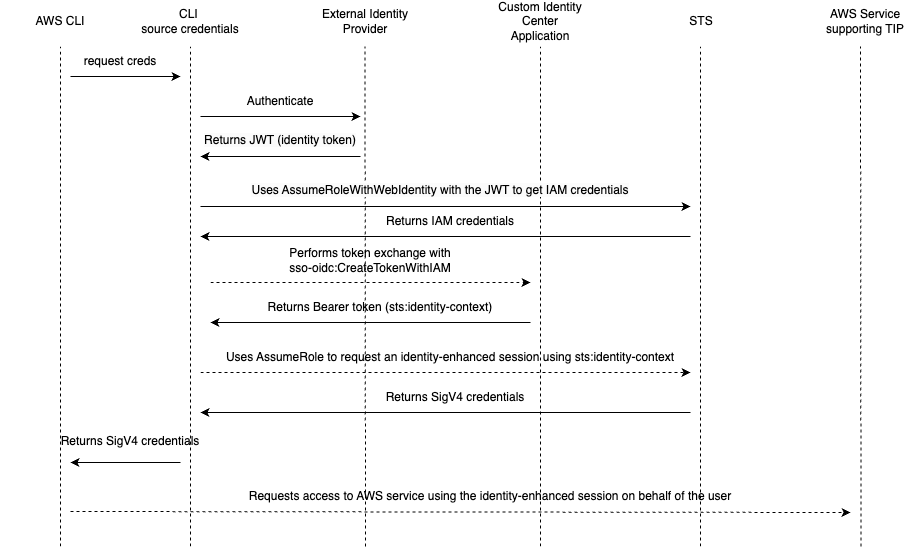
Figure 2 is a swimlane diagram of the requests described in the preceding flow and depicted in Figure 1.

Figure 2: Swimlane diagram of the application token exchange. Dashed lines show SigV4 signed requests

Figure 2: Swimlane diagram of the application token exchange. Dashed lines show SigV4 signed requests

Account prerequisites

In the following procedure, you will use two AWS accounts: one is the application account, where required IAM roles and OIDC federation will be deployed and where users will be granted access to Amazon S3 objects. This account already has S3 Access Grants and an Athena workgroup configured with IAM Identity Center. If you don’t have these already configured, see Getting started with S3 Access Grants and Using IAM Identity Center enabled Athena workgroups.

The other account is the Identity Center admin account which has IAM Identity Center set up with users and groups synchronized through SCIM with your IdP of choice, in this case Okta directory. The application also supports Entra ID and Amazon Cognito.

You don’t need to have permission sets configured with IAM Identity Center, because you will grant access through a customer managed application Identity Center. Users authenticate with the source IdP and don’t interact with an AWS account or IAM policy directly.

To configure this application, you’ll complete the following steps:

  1. Create an OIDC application in Okta
  2. Create a customer managed application in IAM Identity Center
  3. Install and configure the application with the AWS CLI

Create an OIDC application in Okta

Start by creating a custom application in Okta, which will act as the source IdP, and configuring it as a trusted token issuer in IAM Identity Center.

To create an OIDC application

  1. Sign in to your Okta administrator panel, go to the Applications section in the navigation pane, and choose Create App Integration. Because you’re using a CLI, select OIDC as the sign-in method and Native Application as the application type. Choose Next.

    Figure 3: Okta screen to create a new application

    Figure 3: Okta screen to create a new application

  2. In the Grant Type section, the authorization code is selected by default. Make sure to also select Refresh Token. The CLI application uses the refresh tokens if available to generate new access tokens without requiring the user to re-authenticate. Otherwise, the users will have to authenticate again when the token expires.
  3. Change the sign-in redirect URIs to http://localhost:8090/callback. The application uses OAuth 2.0 Authorization Code with PKCE Flow and waits for confirmation of authentication by listening locally on port 8090. The IdP will redirect your browser to this URL to send authentication information after successful sign-in.
  4. Select the directory groups that you want to have access to this application. If you don’t want to restrict access to the application, choose Allow Everyone. Leave the remaining settings as-is.

    Note: You must also assign and authorize users in AWS to allow access to the downstream AWS services.

    Figure 4: Configure the general settings of the Okta application

    Figure 4: Configure the general settings of the Okta application

  5. When done, choose Save and your Okta custom application will be created and you will see a detail page of your application. Note the Okta Client ID value to use in later steps.

Create a customer managed application in IAM Identity Center

After setting everything up in Okta, move on to creating the custom OAuth 2.0 application in IAM Identity Center. The CLI will use this application to exchange the tokens issued by Okta.

To create a customer managed application

  1. Sign in to the AWS Management Console of the account where you already have configured IAM Identity Center and go to the Identity Center console.
  2. In the navigation pane, select Applications under Application assignments.
  3. Choose Add application in the upper
  4. Select I have an application I want to set up and select the OAuth 2.0 type.
  5. Enter a display name and description.
  6. For User and group assignment method, select Do not require assignments (because you already configured your user and group assignments to this application in Okta). You can leave the Application URL field empty and select Not Visible under Application visibility in AWS access portal, because you won’t access the application from the Identity Center AWS access portal URL.
  7. On the next screen, select the Trusted Token Issuer you set up in the prerequisites, and enter your Okta client ID from the Okta application you created in the previous section as the Aud claim. This will make sure your Identity Center custom application only accepts tokens issued by Okta for your Okta custom application.

    Note: Automatically refresh user authentication for active application sessions isn’t needed for this application because the CLI application already refreshes tokens with Okta.

    Figure 5: Trusted token issuer configuration of the custom application

    Figure 5: Trusted token issuer configuration of the custom application

  8. Select Edit the application policy and edit the policy to specify the application account AWS Account ID as the allowed principal to perform the token exchange. You will update the application policy with the Amazon Resource Name (ARN) of the correct role after deploying the rest of the solution.
  9. Continue to the next page to review the application configuration and finalize the creation process.

    Figure 6: Configuration of the application policy

    Figure 6: Configuration of the application policy

  10. Grant the application permission to call other AWS services on the users’ behalf. This step is necessary because the application will use a custom application to exchange tokens that will then be used with specific AWS services. Select the Customer managed tab, browse to the application you just created, and choose Specify trusted applications at the bottom of the page.
  11. For this example, select All applications for service with same access, and then select Athena, S3 Access Grants, and Lake Formation and AWS Glue data catalog as trusted services because they’re supported by the sample application. If you don’t plan to use your CLI with S3 or Athena and Lake Formation, you can skip this step.

    Figure 7: Configure application user propagation

    Figure 7: Configure application user propagation

You have completed the setup within IAM Identity Center. Switch to your application account to complete the next steps, which will deploy the backend application.

Application installation and configuration with the AWS CLI

The sample code for the application can be found on GitHub. Follow the instructions in the README file to install the command-line application. You can use the CLI to generate an AWS CloudFormation template to create the required IAM roles for the token exchange process.

To install and configure the application

  1. You will need your Okta OAuth issuer URI and your Okta application client ID. The issuer URI can be found by going to your Okta Admin page, and on the left navigation pane, go to the API page under the Security section. Here you will see your Authorization servers and their Issuer URI. The application client ID is the same as you used earlier for the Aud claim in IAM Identity Center.
  2. In your CLI, use the following commands to generate and deploy the CloudFormation template:
    tip-cli configure generate-cfn-template https://dev-12345678.okta.com/oauth2/default aBc12345dBe6789FgH0 > ~/tip-blog-iam-roles-cfn.yaml
    aws cloudformation deploy --template-file ~/tip-blog-iam-roles-cfn.yaml --stack-name tip-blog-iam-stack --capabilities CAPABILITY_IAM

  3. After the template is created, update the customer managed application policy you configured in step 2 to allow only the IAM role that CloudFormation just created to use the application. You can find this in your CloudFormation console, or by using aws cloudformation describe-stacks --stack-name tip-blog-iam-stack in your terminal.
  4. Configure the CLI by running tip-cli configure idp and entering the IAM roles’ ARN and Okta information.
  5. Test your configuration by running the tip-cli auth command to start the authorization with the configured IdP by opening your default browser and requesting to sign in. In the background, the application will wait for Okta to callback the browser on port 8090 to retrieve the authentication information, and if successful request an Okta OAuth 2.0 token.
  6. You can then run tip-cli auth get-iam-credentials to exchange the token through your trusted IAM role and your Identity Center application for a set of identity-enhanced IAM role session credentials. These expire in 1 hour by default, but you can configure the expiration period by configuring the IAM role used to create the identity-enhanced IAM session accordingly. After you test the setup, you won’t need the CLI anymore because authentication, token refresh, and credentials refresh will be managed automatically through the AWS CLI.

Note: Follow the README instructions on configuring your AWS CLI to use the tip-cli application to source credentials. The advantage of the solution is that the AWS CLI will automatically handle the refresh of tokens and credentials using this application.

Now that the AWS CLI is configured, you can use it to call AWS services representing your Okta identity. In the following examples, we configured the AWS CLI to use the application to source credentials for the AWS CLI profile my-tti-profile.

For example, you can query Athena tables through workgroups configured with trusted identity propagation and authorized through Lake Formation:

QUERY_EXECUTION_ID=$(aws athena start-query-execution \
    --query-string "SELECT * FROM db_tip.table_example LIMIT 3" \
    --work-group "tip-workgroup" \
    --profile my-tti-profile \
    --output text \
    --query 'QueryExecutionId')

aws athena get-query-results \
    --query-execution-id $QUERY_EXECUTION_ID \
    --profile my-tti-profile \
    --output text

The IAM role used by the backend application to create the identity-enhanced IAM session is allowed by default to use only Athena and Amazon S3. You can extend it to allow access to other services, such as Amazon Q Business. After you create an Amazon Q Business application and assign users to it, you can update the custom application you created earlier in IAM Identity Center and enable trusted identity propagation to your Amazon Q Business application.

You can then, for example, retrieve conversations of the user for an Amazon Q business application with ID a1b2c3d4-5678-90ab-cdef-EXAMPLE11111 as follows:

aws qbusiness list-conversations --application-id a1b2c3d4-5678-90ab-cdef-EXAMPLE11111 --profile my-tti-profile

The application also provides simplified access to S3 Access Grants. After you have configured the AWS CLI as documented in the README file, you can access S3 objects as follows:

aws s3 ls s3://<my-test-bucket-with-path> --profile my-tti-profile-s3ag

In this example, the AWS CLI uses the custom credential source to request data access to a specific S3 URI to the account instance of S3 Access Grants you want to target. If there’s a matching grant for the requested URI and your user identity or group, S3 Access Grants will return a new set of short-lived IAM credentials. The tip-cli application will cache these credentials for you and prompt you to refresh them whenever needed. You can review the list of credentials generated by the application with the command tip-cli s3ag list-credentials, and clear them with the command tip-cli s3ag clear-credentials.

Conclusion

In this post we showed you how a sample CLI application using trusted identity propagation works, enabling business users to bring their workforce identities for delegated access into AWS without needing IAM credentials or cloud backends.

You set up custom applications within Okta (as the directory service) and IAM Identity Center and deployed the required application IAM roles and federation into your AWS account. You learned the architecture of this solution and how to use it in an application.

Through this setup, you can use the AWS CLI to interact with AWS services such as S3 Access Grants or Athena on behalf of the directory user without the having to configure an IAM user or credentials for them.

The code used in this post is also published as an AWS Sample, which can be found on GitHub and is meant to serve as inspiration for integrating custom or third-party applications with trusted identity propagation.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Roberto Migli

Roberto Migli
Roberto is a Principal Solutions Architect at AWS. He supports global financial services customers, focusing on security and identity and access management. In his free time, he enjoys building electronic gadgets, learning about space, and spending time with his family.

Alessandro Fior

Alessandro Fior
Alessandro is a Sr. Data Architect at AWS Professional Services. He is passionate about designing and building modern and scalable data platforms that boost companies’ efficiency in extracting value from their data.

Bruno Corijn

Bruno Corijn
Bruno is a Cloud Infrastructure Architect at AWS based out of Brussels, Belgium. He works with Public Sector customers to accelerate and innovate in their AWS journey, bringing a decade of experience in application and infrastructure modernisation. In his free time he loves to ride and tinker with bikes.

AI 101: Why RAG Is All the RAGe

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/ai-101-why-rag-is-all-the-rage/

A decorative image showing an AI chip connecting icons of representing different files.

At the risk of being called the stick in the mud of the tech world, we here at Backblaze have often bemoaned our industry’s love of making up new acronyms. The most recent culprit, hailing from the fast-moving artificial intelligence/machine learning (AI/ML) space, is truly memorable: RAG, aka retrieval-augmented generation. For the record, its creator has apologized for inflicting it upon the world.

Given how useful it is, we’re willing to forgive. (I’m sure he was holding his breath for that news.) Today, our AI 101 series is back to talk about what RAG is—and the big problem it solves. 

Read more AI 101

This article is part of a series that attempts to understand the evolving world of AI/ML. Check out our previous articles for more context:

Let’s start with large language models (LLMs)

LLMs are the most recognizable expression of AI in our current zeitgeist. (Arguably, you could append that with “that we’re all paying attention to,” given that ML algorithms have been behind many tools for decades now.) LLMs underpin tools like ChatGPT, Google Gemini, and Claude, as well as things like service-oriented chatbots, natural language processing tasks, and so on. They’re trained on vast amounts of data with algorithmic guardrails known as parameters and hyperparameters guiding their training. Once trained, we query them through a process known as inference. 

Fabulous! The possibilities are endless. However, one of the biggest challenges we’ve experienced (and laughed about on the internet) is that LLMs can return inaccurate results, while sounding very, very reasonable. Additionally, LLMs don’t know what they don’t know. Their answers can only be as good as the data they draw from—so, if their training dataset is outdated or contains a systematic bias, it will impact your results. As AI tools have become more widely adopted, we’ve seen LLM inaccuracies range from “funny and widely mocked” to “oh, that’s actually serious.”

Enter retrieval-augmented generation (Fine! RAG)

RAG is a solution to these problems. Instead of relying on only an LLM’s dataset, RAG queries external sources before returning a response. It’s more complicated than “let me google that for you,” as the process takes that external data, turns it into a vectored database, and then balances external data with an LLM’s “general knowledge” generated response and skill at responding to conversational queries. 

This has several advantages. Users now have sources they can cite, and recent information is taken into account. From a development perspective, it means that you don’t have to re-train a model as frequently. And, it can be implemented in as few as five lines of code. 

One important nuance is that when you’re building RAG into your product, you can set its sources. For industries like medicine and law, that means you can point them towards industry journals and trusted sources, outweighing the often misquoted or mis-cited examples you might see in a general database. 

Another example: For a technical documentation portal, you can take an LLM, trained on general information and the nuts and bolts of conversational querying, and direct it to rely on your organization’s help articles as its most important sources. Your organization controls the authoritative data, and how often/when changes are made. Users can trust that they’re getting the most recent security patches and correct code. And, you can do so quickly, easily, and—most importantly—cost-effectively. 

RAG doesn’t mean foolproof AI

RAG is a great, straightforward method for keeping LLM tools updated with current, high-quality information and giving users more transparency around where their answers are coming from. However, as we mentioned above, AI is only ever as good as the data it uses. Keep in mind, that’s a deceptively simple thing to say. It’s an entire, specialized job to validate datasets, and that expertise is built into the research and monitoring that happens while training an LLM. 

RAG gives a new source of data a privileged position—you’re saying “this data is more authoritative than that data” and, since the LLM doesn’t have anything in its general database, it may not have a counter argument. If you’re not paying attention to your RAG data source standards, and doing so on an ongoing basis, it’s possible, and even likely, that data bias, low quality data, etc. could creep into your model. 

Think of it this way: If you’re pointing to a new feature in your tech docs and there’s an error, that impact is magnified because an LLM will give more weight to the RAG data. At least in that case, you’re the one who controls the source data. In our other examples of legal or medical AI tools pointing to journal updates, things can get, well, more complicated. If (when) you’re setting up an AI that uses RAG, it’s imperative to make sure you’re also setting yourself up with reliable sources that are regularly updated. 

But, given its impact, and how low of a lift it is to integrate into existing products, we can see why RAG is all the RAGe—and, as always, we look forward to more to come in the AI landscape. For now, we can already see the impact it’s having on the market, with SaaS companies and startups alike exploring the possibilities.

The post AI 101: Why RAG Is All the RAGe appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

[$] Python grapples with Apple App Store rejections

Post Syndicated from jzb original https://lwn.net/Articles/979671/

An upgrade from Python 3.11 to 3.12 has led to the rejection of
some Python apps by Apple’s app stores. That led to Eric Froemling submitting a bug report
against CPython. That, in turn, led to an interesting
discussion among Python developers about how far the project was
willing to go to accommodate app store review processes. Developers
reached a quick consensus, and a solution that may arrive as soon as
Python 3.13.

Coolest Projects 2024: 7197 young tech creators showcase their projects online

Post Syndicated from Helen Gardner original https://www.raspberrypi.org/blog/coolest-projects-2024-young-tech-creators-showcase-their-projects-online/

Our Coolest Projects 2024 online showcase has come to a close, with 7197 young people from 43 countries sharing the incredible things they have made with code. A huge congratulations to everyone who took part!

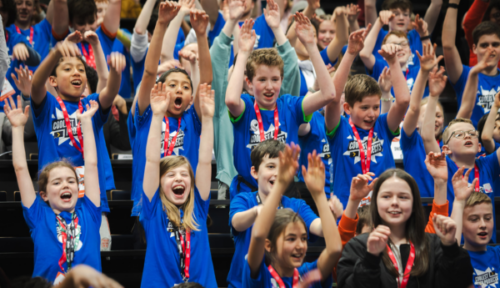
Young people raising their hands in the air.

Coolest Projects is our annual global celebration of young digital creators and the cool things they make with technology. This year’s showcase featured 4678 amazing projects, from a doughnut clicker game created in Scratch to an app that tracks sunscreen usage and areas with high UV levels for users. 

This week, we celebrated each and every young creator and their incredible tech projects in a special livestream:

Every year, we invite some very special VIP judges to choose their favourite projects to highlight. Meet our 2024 judges and find out about the projects they picked.

Azra Ismail’s favourite projects

Azra is the co-founder of MakerGhat, an education nonprofit based in India that aims to nurture underserved youth to become the next generation of entrepreneurs and leaders. MakerGhat has reached around a million youth to date through hands-on making programmes. She is also an Assistant Professor at Emory University, where she directs the CARE Lab (Collective Action & Research for Equity). Azra was named in the Forbes 30 under 30 Asia list, and has previously worked with Google, the Wadhwani Institute for AI, and United Nations Global Pulse. She has a PhD in Human-Centered Computing and Bachelor’s in Computer Engineering from Georgia Tech. 

See Azra’s favourite projects:

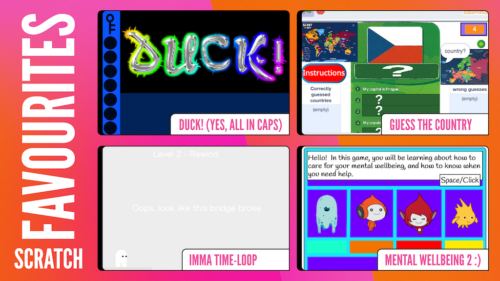
Judges’ favourite projects in the Scratch category.

Greg Foot’s favourite projects

Greg is an award-winning Science Presenter and Producer who has written and hosted a bunch of stuff on TV, YouTube, radio, and stage over the past 20 years. Greg has a BBC Radio 4 show called Sliced Bread that investigates whether wonder products like face creams and air fryers are indeed ‘the best thing since sliced bread’, or marketing hype. Greg regularly pops up on TV — he’s a regular on the BBC’s Morning Live and was the in-house science guy on Blue Peter and Sunday Brunch for many years. He’s also hosted multiple TV series, made live shows for families on YouTube (Let’s Go Live), and toured science theatre shows around the UK.

Take a look at Greg’s favourite projects:

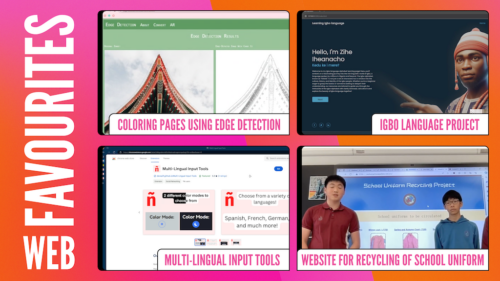
Judges’ favourite projects in the Web category.

Natalie Lao’s favourite projects

Natalie is the Executive Director of the App Inventor Foundation, a global nonprofit that has empowered over 20 million inventors of all ages to create over 100 million apps to improve their lives and uplift their communities. She received her PhD in ML and AI education from MIT’s Computer Science and Artificial Intelligence Lab, and currently serves as Expert on Mission at UNESCO to develop the UN’s AI Competency Framework for K-12 Students. 

See which projects Natalie chose as her favourites:

Judges’ favourite projects in the Games category.

Selin Ornek’s favourite projects

Selin is a 17-year-old multi-award winner and changemaker who has been passionate about using tech for good since an early age. She taught herself to code at age 8 and started building robots at 10, and participated in Coolest Projects for many years. She has built seven robots to date, including the social good robot iC4U, a robot guide dog for visually impaired people, and BB4All, an anti-bullying school aid robot. She has also built a stray dog wellbeing app, JAVA, and an AI model for breast cancer diagnosis. Her aim is to inspire young people, especially girls, to see the fun and importance of using tech for good.

Selin’s favourite projects are:

Judges’ favourite projects in the Mobile category.

Broadcom Coding with Commitment® award

We partnered with Broadcom Foundation to give a special award to young creators using coding and computing to solve real-world problems that matter to their communities. Broadcom Coding with Commitment® is a special recognition for a Coolest Projects creator aged 11–14 who has used computing as an essential problem-solving tool to help those around them.

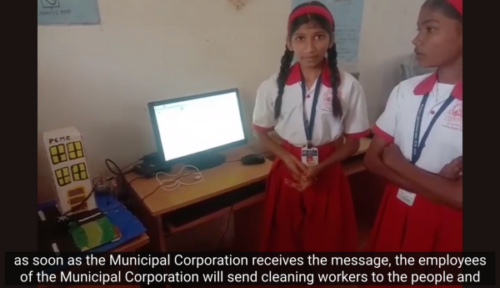
Naitik, Shravasti and Nikita present their 'Drainage alert system' project.

This year’s Broadcom Coding with Commitment® recipients are Naitik, Shravasti, and Nikita from India in recognition of their project Drainage alert system. Their thoughtful project uses a water flow sensor connected to a Raspberry Pi computer to detect when waste enters the drainage system and causes blockages and send an alert to the local council.

Get inspired and keep creating!

Now you’ve seen the judges’ favourite projects, it’s time to pick your own! Take a look at the Coolest Projects 2024 online showcase gallery to see all the amazing projects from young people all over the world, and get inspired to make your own.

Judges’ favourite projects in the Hardware category.

Participants will shortly receive their own unique certificates and the personalised feedback on their projects from our team of judges, to celebrate their achievements.

Judges’ favourite projects in the Advanced category.

Support from our Coolest Projects sponsors means we can make the online showcase and celebration livestream an inspiring experience for the young people taking part. We want to say a big thank you to all of them: Amazon Future Engineer, Broadcom Foundation, GoTo, Kingston Technology, Meta, and Qube Research & Technologies.

The post Coolest Projects 2024: 7197 young tech creators showcase their projects online appeared first on Raspberry Pi Foundation.

Security updates for Thursday

Post Syndicated from jzb original https://lwn.net/Articles/979847/

Security updates have been issued by Debian (ffmpeg, kernel, libvpx, and linux-5.10), Fedora (chromium, firefox, freeipa, moodle, and openvpn), Oracle (git), Red Hat (golang and java-1.8.0-ibm), and Ubuntu (linux-oracle-6.5, netplan.io, openssl, plasma-workspace, ruby2.7, ruby3.0, ruby3.1, sqlite3, and wget).

Слонът в стаята на българския правопис

Post Syndicated from original https://www.toest.bg/slonut-v-stayata-na-bulgharskiya-pravopis/

Слонът в стаята на българския правопис

От десетилетия е там, но ние продължаваме публично да мълчим за него, продължаваме да игнорираме вероятно най-големия проблем в съвременния български правопис. И не, според мен това не са правилата за поставяне на пълен и кратък член, а за слято, полуслято и разделно писане.

Да разчленим проблема

Наистина ли е толкова сложно и трудно да се справим с тези правила? Ще се опитам да обясня в какво се състои проблемът, а отговорът на въпроса, мисля, няма да затрудни никого.

1. Правилата за слято, полуслято и разделно писане са много на брой – между 110 и 1201 .

За сравнение, следващият по обем раздел – за употреба на главни и малки букви – съдържа около 70 правила. Няма какво толкова да се коментира и анализира. И при най-добро желание редовият българин ще се обезсърчи само като се изправи пред такова количество разпоредби в един раздел.

2. Прилагането на правилата изисква време и способности за лингвистичен анализ.

Понеже летните жеги настъпиха със страшна сила още през юни, да се поразхладим с едно айскафе. Случаят е сравнително прост: имаме сложно съществително име, в което двете части са от чужд произход и първата пояснява втората. Тъй като айс не се употребява като самостоятелна дума в българския език, айскафе се пише слято. Ако си пием напитката в кафе-ресторанта обаче, ще трябва да прибегнем до полуслятото писане, защото тук смисловото отношение между двете части е равноправно: заведението е кафе(не) и ресторант.

В случай че бързаме, може да си вземем кофеиновата доза от уличен кафе автомат/кафеавтомат. При тази сложна дума първата част пояснява втората и смисловото отношение е както при айскафе, но понеже и двете части (кафе и автомат) се употребяват самостоятелно, сложната дума може да се пише и слято, и разделно. В практиката масово се предпочита разделното писане в този случай, който може да илюстрираме с примери като фитнес клуб, бизнес среща, рок група2.

При прилагането на някои правила е нужен по-обстоен анализ. Как например следва да пишем компютърно-томографски и ядрено-магнитен? И за двете прилагателни кодификаторът още не се е произнесъл, затова ще се наложи да се заровим в словообразуването и във… физиката. За да напишем правилно първата дума, е нужно само: 1) да знаем, че ако едно сложно прилагателно е образувано от съчетание на прилагателно и съществително име, то се пише слято; 2) да предположим, че има уред, наречен компютърен томограф; 3) да се уверим, че уредът съществува наистина. Е, вече уверено може да напишем компютърнотомографски.

Второто прилагателно обаче явно не може да се свърже с ядрен магнит или с някакво подобно словосъчетание. Затова зарязваме за неопределено време текста, по който работим, и започваме да проучваме физичното явление ядрено-магнитен резонанс, стоящо в основата на едноименното медицинско изследване. Разбираме, че става въпрос за атомни ядра на вещество, поставено в магнитно поле. След като ядро/ядрен не пояснява магнит/магнитен, нито пък обратното, е логично да приемем, че са в равноправни смислови отношения в прилагателното, и да напишем ядрено-магнитен. А колко ценно време загубихме?

3. Част от правилата за слято, полуслято и разделно писане не могат да се приложат обективно.

Най-ярка илюстрация е слятото/разделното писане на сложни прилагателни от типа световноизвестен/безследно изчезнал, които се срещат доста по-често, отколкото може да предположите. В първия пример съчетанието от наречие (световно) и прилагателно име (известен) образуват смислово единство, а във втория – не (тук втората част изчезнал е причастие, функциониращо като прилагателно име). В пощата на „Как се пише?“ вече са ми задавали десетки, ако не и стотици въпроси за правописа на такива прилагателни имена. И това е съвсем естествено, защото, когато слято написаната дума липсва в Официалния правописен речник (вече в БЕРОН), човек изпада в двоумение, а и в триумение как да я напише.

Лютеницата едросмляна ли е, или едро смляна? Обучението проектнобазирано ли е, или проектно базирано (досега съм получила 15 въпроса конкретно за това съчетание!)? Кучетата от породата „Басет“ средноголеми ли са, или средно големи? Едно е сигурно: полуслетият вариант се изключва и е добре това да се уточни, защото немалко питащи всъщност се колебаят между трите начина на писане.

Кой трябва да определи дали дадено съчетание от наречие и прилагателно име/причастие вече представлява смислово единство, тоест едно цялостно понятие, и съответно се е лексикализирало, станало е нова дума в езика? Нима тази задача се вменява на пишещия, който в общия случай не е филолог? Но дори и да е филолог, той не притежава компетентността на висококвалифицирания специалист лексикограф. Според мен конкретно тези правила са едно от най-големите недоразумения в българския правопис и издават определена кодификаторска немощ.

Да продължим със сложните наречия. Правилото в този вид, в който е формулирано, не е кой знае колко полезно:

Сложни наречия, образувани от предлог и наречие, се пишат слято.

За досега, отскоро, вдясно се съгласяваме, че се подчиняват на правилото, но как да се досетим, че до утре, от вчера, в повече са на друг правописен режим? Добре че подобни съчетания не са необозримо много и може да се запомнят от хората, които са паметливи и държат на правописа.

4. При правилата за слято, полуслято и разделно писане има непоследователност, противоречия, ненужни изключения.

Нали си спомняте, че съществителното име кафе автомат може да се пише и разделно, и слято (кафеавтомат), защото двете му части (от чужд произход) се употребяват самостоятелно? Би следвало това да важи например за кинопремиера и радиопрограма. Ами не, не важи, защото думи от този тип се пишат слято по традиция.

Понеже сме на вълна Европейско първенство по футбол, да отбележим и една актуална дума с традиционно слят правопис – голмайстор. Но пък голлиния не е в този списък и може да се пише и слято, и разделно. Изпуснахте ли вече логиката? Добре, ще ви върна в нейното лоно: голлинията е на същия режим като кафеавтомата. И тъкмо нещата да се прояснят и да си дойдат на мястото, макар и с цената на известно умствено напрежение, ще изтичаме до тъчлинията, която трябва да се пише само слято. Същото важи и за аутлинията. Не ме питайте защо. И тъч, и аут се употребяват като самостоятелни съществителни имена в българския език, следователно разделното писане трябва да е позволено.

Ако продължавате да четете, със сигурност сте хвърлени в тъч и ви предлагам там да си останете, за да понесете по-лесно още едно противоречие, което може и да сте установили, в случай че сте се замисляли по въпроса.

Няма логика – нито филологическа, нито обикновена човешка – вкъщи да се пише слято, а у дома – разделно.

И двете представляват съчетание на предлог и стара падежна форма на съществително име3. Когато се променя правописът на дадена дума, редно е да се държи сметка за цялата система. Щом си казал А (вече ще пишем вкъщи), трябва да кажеш и Б (вече ще пишем удома). Иначе дискредитираш въпросната система.

Какво да се прави?

Представих ви само част от проблемите, свързани със слятото, полуслятото и разделното писане, но и те са достатъчни, за извода, че в сегашния си вид правописните правила затрудняват значително не само средностатистическия българин, но и филолозите. Главната причина за тази зле функционираща система от правила според мен е в погрешната концепция, която е стъпила на смисловите отношения между частите, изграждащи сложните думи. Така смята и професор Боян Вълчев:

В частта за слятото, полуслятото и разделното писане […] последователно се говори за главна и подчинена основа, за равноправно и неравноправно отношение […]. Това означава, че когато човек пише, трябва да спре и да направи лингвистичен анализ на думата или думите и тогава да реши как да постъпи. Дори и аз в много от случаите не мога еднозначно да си обясня бързо коя е главната и коя – подчинената основа. Това е постановка, която по принцип е погрешна. Правописът трябва да има почти напълно автоматичен характер.

Ако наистина искаме правилата за слято, полуслято и разделно писане да са функционални, с козметични промени нищо няма да се постигне. Нужна е промяна на концепцията, която да се основава на структурата на думите, а не на смисловите отношения между частите им. Лошото е, че белята вече е направена – макар и лоши, правилата са познати и хората, които държат на правописа, са свикнали с тях. Затова кардинална промяна ще се посрещне, меко казано, с неодобрение. Зле е, но е познатото зле. Би ли имал смелост кодификаторът да предприеме такава промяна? Надявам се, че поне мисли върху нея.

1 Поради начина, по който са формулирани, и поради включването на някои правила в различни подраздели е трудно броят им да се прецизира.

2 Правилно е също да се пише фитнесклуб, бизнессреща, рокгрупа.

3 Дома е падежна, а не членувана форма на съществителното дом, както биха възразили някои, и доказателство е най-малкото това, че произнасяме [домà], а не [домъ̀].


Езикът може да е вкусен и извън блюдото – онзи, българският език, на който говорим от малки и на който около 24 май се кълнем в обич. А той в същността си е средство за общуване и за да ни служи добре, непрекъснато се променя. Да го погледнем в неговата динамика и да се опитаме да разберем какво става и защо, кои са движещите механизми и как те са свързани с обществените процеси. И тъй като задачата не е лека, ще го правим постепенно – на порции.

Let’s Architect! Migrating to the cloud with AWS

Post Syndicated from Federica Ciuffo original https://aws.amazon.com/blogs/architecture/lets-architect-migrating-to-the-cloud-with-aws/

In today’s digital world, businesses are increasingly turning to the cloud for its scalability, agility, and cost-effectiveness. Migrating your data center to the cloud can be a daunting task, but with the right approach and tools, it can be a successful journey. This Let’s Architect! blog post will guide you through the process of migrating to the cloud with AWS, leveraging the proven AWS Cloud Adoption Framework (AWS CAF) and exploring valuable resources to help you navigate each step.

AWS Cloud Adoption Framework

The AWS Cloud Adoption Framework (CAF) provides a comprehensive approach to planning, designing, and deploying your cloud migration. This robust framework outlines a four-phase methodology that guides you through every stage of the process, from strategy and planning to ongoing management and optimization. Here’s a closer look at the four phases of the AWS CAF:

  • Envision: Identify business transformation opportunities that align with your strategic goals and demonstrate how the cloud will accelerate your business outcomes.
  • Align: Assess your organization’s cloud readiness by identifying capability gaps across six key perspectives (Business, People, Governance, Platform, Security, and Operations). Address these gaps by developing strategies, ensuring stakeholder alignment, and implementing relevant change management activities.
  • Launch: Select impactful pilot initiatives and deploy them in production. These pilots should showcase the value proposition of the cloud and provide valuable insights for further refinement.
  • Scale: Focus on expanding production pilots and business value to desired scale and ensuring that the business benefits associated with your cloud investments are realized and sustained.
The AWS CAF recommends four iterative and incremental cloud transformation phases

Figure 1. The AWS CAF recommends four iterative and incremental cloud transformation phases

Take me to this whitepaper!

Large-scale migration and modernization

Migrating a large-scale data center to the cloud requires careful planning and execution. This video session focuses on valuable lessons learned from the thousands of enterprises who have migrated and modernized their on-premises workloads with AWS. Dive deep on technical lessons learned, mental models used, how to set up teams to modernize as they migrate, and how to engage with AWS Professional Services and AWS Partners for success. Finally, you will get insights on the latest AWS migration and modernization tools.

Migrating to AWS Cloud unlocked major benefits for Live Nation, including a 58% cost saving

Figure 2. Migrating to AWS Cloud unlocked major benefits for Live Nation, including a 58% cost saving

Take me to this video!

Dive deep into different AWS DMS migration options

At the heart of any successful data migration lies a robust database migration strategy. AWS Database Migration Service (AWS DMS) empowers you with a comprehensive suite of tools to seamlessly move and replicate your data. This session explains the various options offered by AWS DMS, including logical replication, managed native methods for export, import, and replication, and bulk extract and load functionalities. Through these options, you’ll gain a thorough understanding of how to migrate and replicate your data, along with the distinct advantages of each approach. The session also explores performance considerations to ensure optimal migration efficiency. Finally, you will learn how modern capabilities like serverless technologies, auto scaling, and schema conversion can simplify migrations.

AWS DMS Schema Conversion converts your existing database schemas and a majority of the database code objects to a format compatible with the target database

FIgure 3. AWS DMS Schema Conversion converts your existing database schemas and a majority of the database code objects to a format compatible with the target database

Take me to this video!

Application Migration with AWS

Migrating and modernizing your applications is a crucial aspect of your cloud adoption strategy. The Application Migration with AWS workshop series provides hands-on experience with planning and executing application migrations. You’ll learn practical techniques like database replatforming, application rehosting, and containerization to make your move to the cloud smooth and efficient.

As part of this lab, you will perform a database migration with AWS DMS

Figure 4. As part of this lab, you will perform a database migration with AWS DMS

Take me to this workshop!

But the journey doesn’t end there. As your applications scale in the cloud, managing that growth becomes key. This is where infrastructure as code (IaC) comes in, and AWS CDK takes IaC a step further by allowing you to write infrastructure code in familiar programming languages you already know. This streamlines your migration by leveraging your existing coding knowledge. We recommend this AWS CDK workshop to get started with CDK for infrastructure automation.

See you next time!

Thanks for reading! With this post, we provided resources to help you navigate your cloud migration journey with confidence and success. In the next blog, we will talk about Well-Architected best practices!

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

The collective thoughts of the interwebz