Tag Archives: research

OPAQUE: The Best Passwords Never Leave your Device

Post Syndicated from Tatiana Bradley original https://blog.cloudflare.com/opaque-oblivious-passwords/
OPAQUE: The Best Passwords Never Leave your Device

OPAQUE: The Best Passwords Never Leave your Device

Passwords are a problem. They are a problem for reasons that are familiar to most readers. For us at Cloudflare, the problem lies much deeper and broader. Most readers will immediately acknowledge that passwords are hard to remember and manage, especially as password requirements grow increasingly complex. Luckily there are great software packages and browser add-ons to help manage passwords. Unfortunately, the greater underlying problem is beyond the reaches of software to solve.

The fundamental password problem is simple to explain, but hard to solve: A password that leaves your possession is guaranteed to sacrifice security, no matter its complexity or how hard it may be to guess. Passwords are insecure by their very existence.

You might say, “but passwords are always stored in encrypted format!” That would be great. More accurately, they are likely stored as a salted hash, as explained below. Even worse is that there is no way to verify the way that passwords are stored, and so we can assume that on some servers passwords are stored in cleartext. The truth is that even responsibly stored passwords can be leaked and broken, albeit (and thankfully) with enormous effort. An increasingly pressing problem stems from the nature of passwords themselves: any direct use of a password, today, means that the password must be handled in the clear.

You say, “but my password is transmitted securely over HTTPS!” This is true.

You say, “but I know the server stores my password in hashed form, secure so no one can access it!” Well, this puts a lot of faith in the server. Even so, let’s just say that yes, this may be true, too.

There remains, however, an important caveat — a gap in the end-to-end use of passwords. Consider that once a server receives a password, between being securely transmitted and securely stored, the password has to be read and processed. Yes, as cleartext!

And it gets worse — because so many are used to thinking in software, it’s easy to forget about the vulnerability of hardware. This means that even if the software is somehow trusted, the password must at some point reside in memory. The password must at some point be transmitted over a shared bus to the CPU. These provide vectors of attack to on-lookers in many forms. Of course, these attack vectors are far less likely than those presented by transmission and permanent storage, but they are no less severe (recent CPU vulnerabilities such as Spectre and Meltdown should serve as a stark reminder.)

The only way to fix this problem is to get rid of passwords altogether. There is hope! Research and private sector communities are working hard to do just that. New standards are emerging and growing mature. Unfortunately, passwords are so ubiquitous that it will take a long time to agree on and supplant passwords with new standards and technology.

At Cloudflare, we’ve been asking if there is something that can be done now, imminently. Today’s deep-dive into OPAQUE is one possible answer. OPAQUE is one among many examples of systems that enable a password to be useful without it ever leaving your possession. No one likes passwords, but as long they’re in use, at least we can ensure they are never given away.

I’ll be the first to admit that password-based authentication is annoying. Passwords are hard to remember, tedious to type, and notoriously insecure. Initiatives to reduce or replace passwords are promising. For example, WebAuthn is a standard for web authentication based primarily on public key cryptography using hardware (or software) tokens. Even so, passwords are frustratingly persistent as an authentication mechanism. Whether their persistence is due to their ease of implementation, familiarity to users, or simple ubiquity on the web and elsewhere, we’d like to make password-based authentication as secure as possible while they persist.

My internship at Cloudflare focused on OPAQUE, a cryptographic protocol that solves one of the most glaring security issues with password-based authentication on the web: though passwords are typically protected in transit by HTTPS, servers handle them in plaintext to check their correctness. Handling plaintext passwords is dangerous, as accidentally logging or caching them could lead to a catastrophic breach. The goal of the project, rather than to advocate for adoption of any particular protocol, is to show that OPAQUE is a viable option among many for authentication. Because the web case is most familiar to me, and likely many readers, I will use the web as my main example.

Web Authentication 101: Password-over-TLS

When you type in a password on the web, what happens? The website must check that the password you typed is the same as the one you originally registered with the site. But how does this check work?

Usually, your username and password are sent to a server. The server then checks if the registered password associated with your username matches the password you provided. Of course, to prevent an attacker eavesdropping on your Internet traffic from stealing your password, your connection to the server should be encrypted via HTTPS (HTTP-over-TLS).

Despite use of HTTPS, there still remains a glaring problem in this flow: the server must store a representation of your password somewhere. Servers are hard to secure, and breaches are all too common. Leaking this representation can cause catastrophic security problems. (For records of the latest breaches, check out https://haveibeenpwned.com/).

To make these leaks less devastating, servers often apply a hash function to user passwords. A hash function maps each password to a unique, random-looking value. It’s easy to apply the hash to a password, but almost impossible to reverse the function and retrieve the password. (That said, anyone can guess a password, apply the hash function, and check if the result is the same.)

With password hashing, plaintext passwords are no longer stored on servers.  An attacker who steals a password database no longer has direct access to passwords. Instead, the attacker must apply the hash to many possible passwords and compare the results with the leaked hashes.

Unfortunately, if a server hashes only the passwords, attackers can download precomputed rainbow tables containing hashes of trillions of possible passwords and almost instantly retrieve the plaintext passwords. (See https://project-rainbowcrack.com/table.htm for a list of some rainbow tables).

With this in mind, a good defense-in-depth strategy is to use salted hashing, where the server hashes your password appended to a random, per-user value called a salt. The server also saves the salt alongside the username, so the user never sees or needs to submit it. When the user submits a password, the server re-computes this hash function using the salt. An attacker who steals password data, i.e., the password representations and salt values, must then guess common passwords one by one and apply the (salted) hash function to each guessed password. Existing rainbow tables won’t help because they don’t take the salts into account, so the attacker needs to make a new rainbow table for each user!

This (hopefully) slows down the attack enough for the service to inform users of a breach, so they can change their passwords. In addition, the salted hashes should be hardened by applying a hash many times to further slow attacks. (See https://blog.cloudflare.com/keeping-passwords-safe-by-staying-up-to-date/ for a more detailed discussion).

These two mitigation strategies — encrypting the password in transit and storing salted, hardened hashes — are the current best practices.

A large security hole remains open. Password-over-TLS (as we will call it) requires users to send plaintext passwords to servers during login, because servers must see these passwords to match against registered passwords on file. Even a well-meaning server could accidentally cache or log your password attempt(s), or become corrupted in the course of checking passwords. (For example, Facebook detected in 2019 that it had accidentally been storing hundreds of millions of plaintext user passwords). Ideally, servers should never see a plaintext password at all.

But that’s quite a conundrum: how can you check a password if you never see the password? Enter OPAQUE: a Password-Authenticated Key Exchange (PAKE) protocol that simultaneously proves knowledge of a password and derives a secret key. Before describing OPAQUE in detail, we’ll first summarize PAKE functionalities in general.

Password Proofs with Password-Authenticated Key Exchange

Password-Authenticated Key Exchange (PAKE) was proposed by Bellovin and Merrit in 1992, with an initial motivation of allowing password-authentication without the possibility of dictionary attacks based on data transmitted over an insecure channel.

Essentially, a plain, or symmetric, PAKE is a cryptographic protocol that allows two parties who share only a password to establish a strong shared secret key. The goals of PAKE are:

1) The secret keys will match if the passwords match, and appear random otherwise.

2) Participants do not need to trust third parties (in particular, no Public Key Infrastructure),

3) The resulting secret key is not learned by anyone not participating in the protocol – including those who know the password.

4) The protocol does not reveal either parties’ password to each other (unless the passwords match), or to eavesdroppers.

In sum, the only way to successfully attack the protocol is to guess the password correctly while participating in the protocol. (Luckily, such attacks can be mostly thwarted by rate-limiting, i.e, blocking a user from logging in after a certain number of incorrect password attempts).

Given these requirements, password-over-TLS is clearly not a PAKE, because:

  • It relies on WebPKI, which places trust in third-parties called Certificate Authorities (see https://blog.cloudflare.com/introducing-certificate-transparency-and-nimbus/ for an in-depth explanation of WebPKI and some of its shortcomings).
  • The user’s password is revealed to the server.
  • Password-over-TLS provides the user no assurance that the server knows their password or a derivative of it — a server could accept any input from the user with no checks whatsoever.

That said, plain PAKE is still worse than Password-over-TLS, simply because it requires the server to store plaintext passwords. We need a PAKE that lets the server store salted hashes if we want to beat the current practice.

An improvement over plain PAKE is what’s called an asymmetric PAKE (aPAKE), because only the client knows the password, and the server knows a hashed password. An aPAKE has the four properties of PAKE, plus one more:

5) An attacker who steals password data stored on the server must perform a dictionary attack to retrieve the password.

The issue with most existing aPAKE protocols, however, is that they do not allow for a salted hash (or if they do, they require that salt to be transmitted to the user, which means the attacker has access to the salt beforehand and can begin computing a rainbow table for the user before stealing any data). We’d like, therefore, to upgrade the security property as follows:

5*) An attacker who steals password data stored on the server must perform a per-user dictionary attack to retrieve the password after the data is compromised.

OPAQUE is the first aPAKE protocol with a formal security proof that has this property: it allows for a completely secret salt.

OPAQUE – Servers safeguard secrets without knowing them!
OPAQUE: The Best Passwords Never Leave your Device

OPAQUE is what’s referred to as a strong aPAKE, which simply means that it resists these pre-computation attacks by using a secretly salted hash on the server. OPAQUE was proposed and formally analyzed by Stanislaw Jarecki, Hugo Krawcyzk and Jiayu Xu in 2018 (full disclosure: Stanislaw Jarecki is my academic advisor). The name OPAQUE is a combination of the names of two cryptographic protocols: OPRF and PAKE. We already know PAKE, but what is an OPRF? OPRF stands for Oblivious Pseudo-Random Function, which is a protocol by which two parties compute a function F(key, x) that is deterministic but outputs random-looking values. One party inputs the value x, and another party inputs the key – the party who inputs x learns the result F(key, x) but not the key, and the party providing the key learns nothing.  (You can dive into the math of OPRFs here: https://blog.cloudflare.com/privacy-pass-the-math/).

The core of OPAQUE is a method to store user secrets for safekeeping on a server, without giving the server access to those secrets. Instead of storing a traditional salted password hash, the server stores a secret envelope for you that is “locked” by two pieces of information: your password known only by you, and a random secret key (like a salt) known only by the server. To log in, the client initiates a cryptographic exchange that reveals the envelope key to the client, but, importantly, not to the server.

The server then sends the envelope to the user, who now can retrieve the encrypted keys. (The keys included in the envelope are a private-public key pair for the user, and a public key for the server.) These keys, once unlocked, will be the inputs to an Authenticated Key Exchange (AKE) protocol, which allows the user and server to establish a secret key which can be used to encrypt their future communication.

OPAQUE consists of two phases, being credential registration and login via key exchange.

OPAQUE: Registration Phase

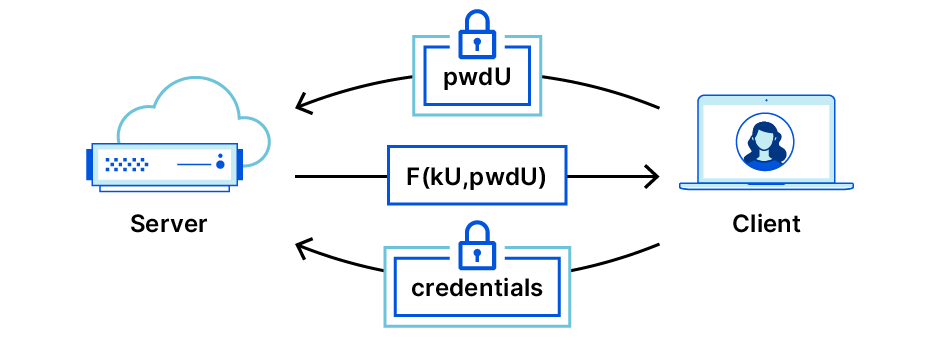
Before registration, the user first signs up for a service and picks a username and password. Registration begins with the OPRF flow we just described: Alice (the user) and Bob (the server) do an OPRF exchange. The result is that Alice has a random key rwd, derived from the OPRF output F(key, pwd), where key is a server-owned OPRF key specific to Alice and pwd is Alice’s password.

Within his OPRF message, Bob sends the public key for his OPAQUE identity. Alice then generates a new private/public key pair, which will be her persistent OPAQUE identity for Bob’s service, and encrypts her private key along with Bob’s public key with the rwd (we will call the result an encrypted envelope). She sends this encrypted envelope along with her public key (unencrypted) to Bob, who stores the data she provided, along with Alice’s specific OPRF keysecret, in a database indexed by her username.
OPAQUE: The Best Passwords Never Leave your Device

OPAQUE: Login Phase

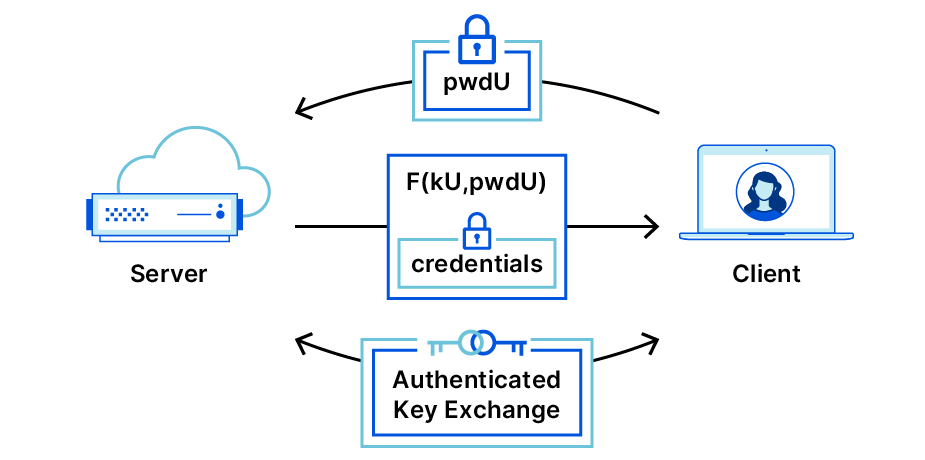
The login phase is very similar. It starts the same way as registration — with an OPRF flow. However, on the server side, instead of generating a new OPRF key, Bob instead looks up the one he created during Alice’s registration. He does this by looking up Alice’s username (which she provides in the first message), and retrieving his record of her. This record contains her public key, her encrypted envelope, and Bob’s OPRF key for Alice.

He also sends over the encrypted envelope which Alice can decrypt with the output of the OPRF flow. (If decryption fails, she aborts the protocol — this likely indicates that she typed her password incorrectly, or Bob isn’t who he says he is). If decryption succeeds, she now has her own secret key and Bob’s public key. She inputs these into an AKE protocol with Bob, who, in turn, inputs his private key and her public key, which gives them both a fresh shared secret key.
OPAQUE: The Best Passwords Never Leave your Device

Integrating OPAQUE with an AKE

An important question to ask here is: what AKE is suitable for OPAQUE? The emerging CFRG specification outlines several options, including 3DH and SIGMA-I. However, on the web, we already have an AKE at our disposal: TLS!

Recall that TLS is an AKE because it provides unilateral (and mutual) authentication with shared secret derivation. The core of TLS is a Diffie-Hellman key exchange, which by itself is unauthenticated, meaning that the parties running it have no way to verify who they are running it with. (This is a problem because when you log into your bank, or any other website that stores your private data, you want to be sure that they are who they say they are). Authentication primarily uses certificates, which are issued by trusted entities through a system called Public Key Infrastructure (PKI). Each certificate is associated with a secret key. To prove its identity, the server presents its certificate to the client, and signs the TLS handshake with its secret key.

Modifying this ubiquitous certificate-based authentication on the web is perhaps not the best place to start. Instead, an improvement would be to authenticate the TLS shared secret, using OPAQUE, after the TLS handshake completes. In other words, once a server is authenticated with its typical WebPKI certificate, clients could subsequently authenticate to the server. This authentication could take place “post handshake” in the TLS connection using OPAQUE.

Exported Authenticators are one mechanism for “post-handshake” authentication in TLS. They allow a server or client to provide proof of an identity without setting up a new TLS connection. Recall that in the standard web case, the server establishes their identity with a certificate (proving, for example, that they are “cloudflare.com”). But if the same server also holds alternate identities, they must run TLS again to prove who they are.

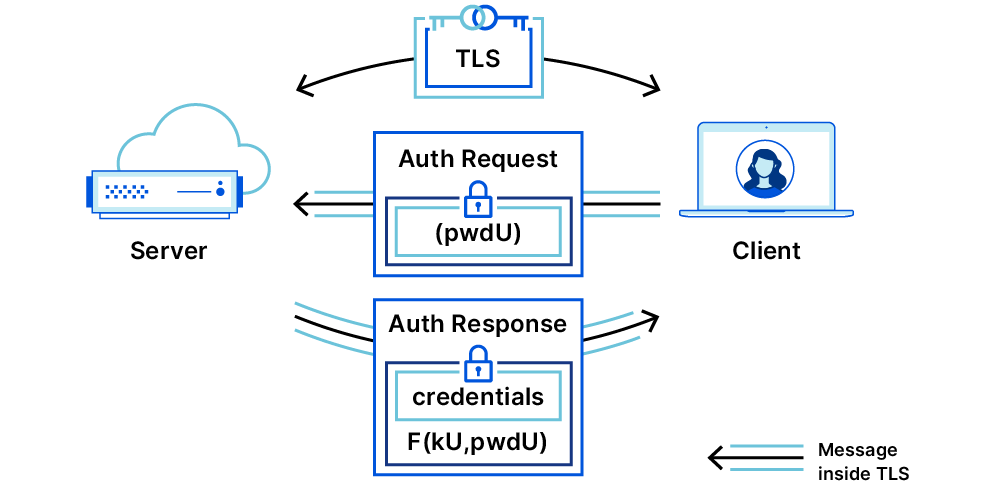
The basic Exported Authenticator flow works resembles a classical challenge-response protocol, and works as follows. (We’ll consider the server authentication case only, as the client case is symmetric).
OPAQUE: The Best Passwords Never Leave your Device

At any point after a TLS connection is established, Alice (the client) sends an authenticator request to indicate that she would like Bob (the server) to prove an additional identity. This request includes a context (an unpredictable string — think of this as a challenge), and extensions which include information about what identity the client wants to be provided. For example, the client could include the SNI extension to ask the server for a certificate associated with a certain domain name other than the one initially used in the TLS connection.

On receipt of the client message, if the server has a valid certificate corresponding to the request, it sends back an exported authenticator which proves that it has the secret key for the certificate. (This message has the same format as an Auth message from the client in TLS 1.3 handshake – it contains a Certificate, a CertificateVerify and a Finished message). If the server cannot or does not wish to authenticate with the requested certificate, it replies with an empty authenticator which contains only a well formed Finished message.

The client then checks that the Exported Authenticator it receives is well-formed, and then verifies that the certificate presented is valid, and if so, accepts the new identity.

In sum, Exported Authenticators provide authentication in a higher layer (such as the application layer) safely by leveraging the well-vetted cryptography and message formats of TLS. Furthermore, it is tied to the TLS session so that authentication messages can’t be copied and pasted from one TLS connection into another. In other words, Exported Authenticators provide exactly the right hooks needed to add OPAQUE-based authentication into TLS.

OPAQUE with Exported Authenticators (OPAQUE-EA)
OPAQUE: The Best Passwords Never Leave your Device

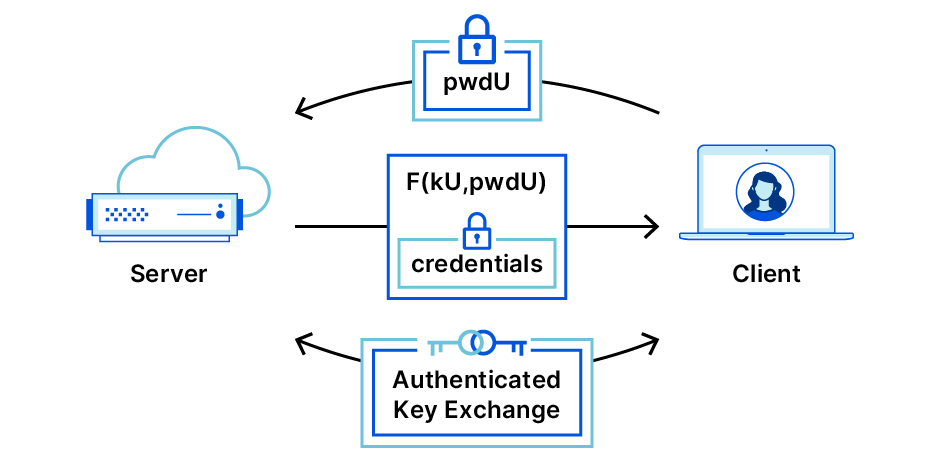
OPAQUE-EA allows OPAQUE to run at any point after a TLS connection has already been set up. Recall that Bob (the server) will store his OPAQUE identity, in this case a signing key and verification key, and Alice will store her identity — encrypted — on Bob’s server. (The registration flow where Alice stores her encrypted keys is the same as in regular OPAQUE, except she stores a signing key, so we will skip straight to the login flow). Alice and Bob run two request-authenticate EA flows, one for each party, and OPAQUE protocol messages ride along in the extensions section of the EAs. Let’s look in detail how this works.

First, Alice generates her OPRF message based on her password. She creates an Authenticator Request asking for Bob’s OPAQUE identity, and includes (in the extensions field) her username and her OPRF message, and sends this to Bob over their established TLS connection.

Bob receives the message and looks up Alice’s username in his database. He retrieves her OPAQUE record containing her verification key and encrypted envelope, and his OPRF key. He uses the OPRF key on the OPRF message, and creates an Exported Authenticator proving ownership of his OPAQUE signing key, with an extension containing his OPRF message and the encrypted envelope. Additionally, he sends a new Authenticator Request asking Alice to prove ownership of her OPAQUE signing key.

Alice parses the message and completes the OPRF evaluation using Bob’s message to get output rwd, and uses rwd to decrypt the envelope. This reveals her signing key and Bob’s public key. She uses Bob’s public key to validate his Authenticator Response proof, and, if it checks out, she creates and sends an Exported Authenticator proving that she holds the newly decrypted signing key. Bob checks the validity of her Exported Authenticator, and if it checks out, he accepts her login.

My project: OPAQUE-EA over HTTPS

Everything described above is supported by lots and lots of theory that has yet to find its way into practice. My project was to turn the theory into reality. I started with written descriptions of Exported Authenticators, OPAQUE, and a preliminary draft of OPAQUE-in-TLS. My goal was to get from those to a working prototype.

My demo shows the feasibility of implementing OPAQUE-EA on the web, completely removing plaintext passwords from the wire, even encrypted. This provides a possible alternative to the current password-over-TLS flow with better security properties, but no visible change to the user.

A few of the implementation details are worth knowing. In computer science, abstraction is a powerful tool. It means that we can often rely on existing tools and APIs to avoid duplication of effort. In my project I relied heavily on mint, an open-source implementation of TLS 1.3 in Go that is great for prototyping. I also used CIRCL’s OPRF API. I built libraries for Exported Authenticators, the core of OPAQUE, and OPAQUE-EA (which ties together the two).

I made the web demo by wrapping the OPAQUE-EA functionality in a simple HTTP server and client that pass messages to each other over HTTPS. Since a browser can’t run Go, I compiled from Go to WebAssembly (WASM) to get the Go functionality in the browser, and wrote a simple script in JavaScript to call the WASM functions needed.

Since current browsers do not give access to the underlying TLS connection on the client side, I had to implement a work-around to allow the client to access the exporter keys, namely, that the server simply computes the keys and sends them to the client over HTTPS. This workaround reduces the security of the resulting demo — it means that trust is placed in the server to provide the right keys. Even so, the user’s password is still safe, even if a malicious server provided bad keys— they just don’t have assurance that they actually previously registered with that server. However, in the future, browsers could include a mechanism to support exported keys and allow OPAQUE-EA to run with its full security properties.

You can explore my implementation on Github, and even follow the instructions to spin up your own OPAQUE-EA test server and client. I’d like to stress, however, that the implementation is meant as a proof-of-concept only, and must not be used for production systems without significant further review.

OPAQUE-EA Limitations

Despite its great properties, there will definitely be some hurdles in bringing OPAQUE-EA from a proof-of-concept to a fully fledged authentication mechanism.

Browser support for TLS exporter keys. As mentioned briefly before, to run OPAQUE-EA in a browser, you need to access secrets from the TLS connection called exporter keys. There is no way to do this in the current most popular browsers, so support for this functionality will need to be added.

Overhauling password databases. To adopt OPAQUE-EA, servers need not only to update their password-checking logic, but also completely overhaul their password databases. Because OPAQUE relies on special password representations that can only be generated interactively, existing salted hashed passwords cannot be automatically updated to OPAQUE records. Servers will likely need to run a special OPAQUE registration flow on a user-by-user basis. Because OPAQUE relies on buy-in from both the client and the server, servers may need to support the old method for a while before all clients catch up.

Reliance on emerging standards. OPAQUE-EA relies on OPRFs, which is in the process of standardization, and Exported Authenticators, a proposed standard. This means that support for these dependencies is not yet available in most existing cryptographic libraries, so early adopters may need to implement these tools themselves.

Summary

As long as people still use passwords, we’d like to make the process as secure as possible. Current methods rely on the risky practice of handling plaintext passwords on the server side while checking their correctness. PAKEs, and (specifically aPAKEs) allow secure password login without ever letting the server see the passwords.

OPAQUE is also being explored within other companies. According to Kevin Lewi, a research scientist from the Novi Research team at Facebook, they are “excited by the strong cryptographic guarantees provided by OPAQUE and are actively exploring OPAQUE as a method for further safeguarding credential-protected fields that are stored server-side.”

OPAQUE is one of the best aPAKEs out there, and can be fully integrated into TLS. You can check out the core OPAQUE implementation here and the demo TLS integration here. A running version of the demo is also available here. A Typescript client implementation of OPAQUE is coming soon. If you’re interested in implementing the protocol, or encounter any bugs with the current implementation, please drop us a line at [email protected]! Consider also subscribing to the IRTF CFRG mailing list to track discussion about the OPAQUE specification and its standardization.
Improving DNS Privacy with Oblivious DoH in 1.1.1.1

Post Syndicated from Tanya Verma original https://blog.cloudflare.com/oblivious-dns/

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

Today we are announcing support for a new proposed DNS standard — co-authored by engineers from Cloudflare, Apple, and Fastly — that separates IP addresses from queries, so that no single entity can see both at the same time. Even better, we’ve made source code available, so anyone can try out ODoH, or run their own ODoH service!

But first, a bit of context. The Domain Name System (DNS) is the foundation of a human-usable Internet. It maps usable domain names, such as cloudflare.com, to IP addresses and other information needed to connect to that domain. A quick primer about the importance and issues with DNS can be read in a previous blog post. For this post, it’s enough to know that, in the initial design and still dominant usage of DNS, queries are sent in cleartext. This means anyone on the network path between your device and the DNS resolver can see both the query that contains the hostname (or website) you want, as well as the IP address that identifies your device.

To safeguard DNS from onlookers and third parties, the IETF standardized DNS encryption with DNS over HTTPS (DoH) and DNS over TLS (DoT). Both protocols prevent queries from being intercepted, redirected, or modified between the client and resolver. Client support for DoT and DoH is growing, having been implemented in recent versions of Firefox, iOS, and more. Even so, until there is wider deployment among Internet service providers, Cloudflare is one of only a few providers to offer a public DoH/DoT service. This has raised two main concerns. One concern is that the centralization of DNS introduces single points of failure (although, with data centers in more than 100 countries, Cloudflare is designed to always be reachable). The other concern is that the resolver can still link all queries to client IP addresses.

Cloudflare is committed to end-user privacy. Users of our public DNS resolver service are protected by a strong, audited privacy policy. However, for some, trusting Cloudflare with sensitive query information is a barrier to adoption, even with such a strong privacy policy. Instead of relying on privacy policies and audits, what if we could give users an option to remove that bar with technical guarantees?

Today, Cloudflare and partners are launching support for a protocol that does exactly that: Oblivious DNS over HTTPS, or ODoH for short.

ODoH Partners:

We’re excited to launch ODoH with several leading launch partners who are equally committed to privacy.

A key component of ODoH is a proxy that is disjoint from the target resolver. Today, we’re launching ODoH with several leading proxy partners, including: PCCW, SURF, and Equinix.

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

“ODoH is a revolutionary new concept designed to keep users’ privacy at the center of everything. Our ODoH partnership with Cloudflare positions us well in the privacy and “Infrastructure of the Internet” space. As well as the enhanced security and performance of the underlying PCCW Global network, which can be accessed on-demand via Console Connect, the performance of the proxies on our network are now improved by Cloudflare’s 1.1.1.1 resolvers. This model for the first time completely decouples client proxy from the resolvers. This partnership strengthens our existing focus on privacy as the world moves to a more remote model and privacy becomes an even more critical feature.” — Michael Glynn, Vice President, Digital Automated Innovation, PCCW Global

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

“We are partnering with Cloudflare to implement better user privacy via ODoH. The move to ODoH is a true paradigm shift, where the users’ privacy or the IP address is not exposed to any provider, resulting in true privacy. With the launch of ODoH-pilot, we’re joining the power of Cloudflare’s network to meet the challenges of any users around the globe. The move to ODoH is not only a paradigm shift but it emphasizes how privacy is important to any users than ever, especially during 2020. It resonates with our core focus and belief around Privacy.” — Joost van Dijk, Technical Product Manager, SURF

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

How does Oblivious DNS over HTTPS (ODoH) work?

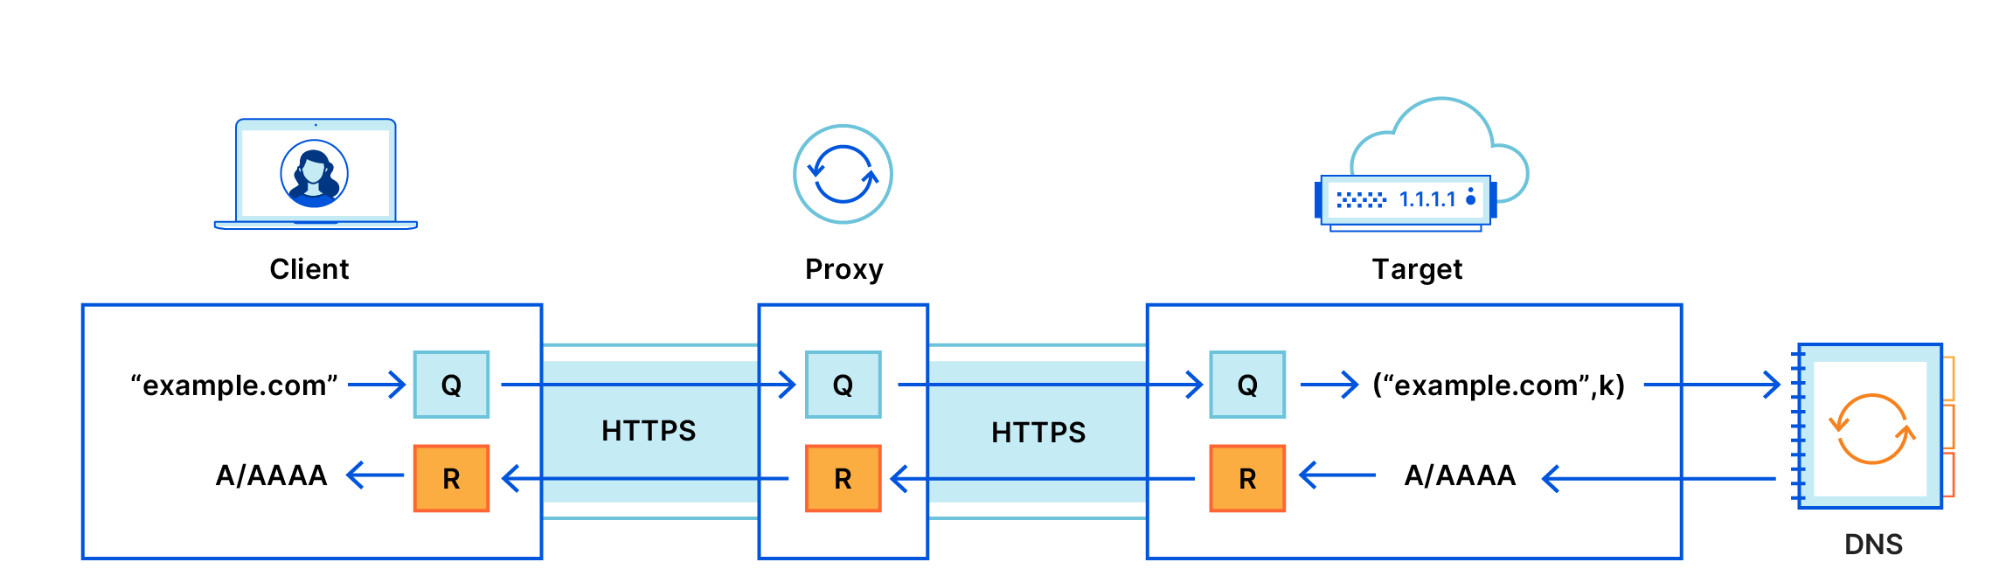
ODoH works by adding a layer of public key encryption, as well as a network proxy between clients and DoH servers such as 1.1.1.1. The combination of these two added elements guarantees that only the user has access to both the DNS messages and their own IP address at the same time.

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

There are three players in the ODoH path. Looking at the figure above, let’s begin with the target. The target decrypts queries encrypted by the client, via a proxy. Similarly, the target encrypts responses and returns them to the proxy. The standard says that the target may or may not be the resolver (we’ll touch on this later). The proxy does as a proxy is supposed to do, in that it forwards messages between client and target. The client behaves as it does in DNS and DoH, but differs by encrypting queries for the target, and decrypting the target’s responses. Any client that chooses to do so can specify a proxy and target of choice.

Together, the added encryption and proxying provide the following guarantees:

  1. The target sees only the query and the proxy’s IP address.
  2. The proxy has no visibility into the DNS messages, with no ability to identify, read, or modify either the query being sent by the client or the answer being returned by the target.
  3. Only the intended target can read the content of the query and produce a response.

These three guarantees improve client privacy while maintaining the security and integrity of DNS queries. However, each of these guarantees relies on one fundamental property — that the proxy and the target servers do not collude. So long as there is no collusion, an attacker succeeds only if both the proxy and target are compromised.

One aspect of this system worth highlighting is that the target is separate from the upstream recursive resolver that performs DNS resolution. In practice, for performance, we expect the target to be the same. In fact, 1.1.1.1 is now both a recursive resolver and a target! There is no reason that a target needs to exist separately from any resolver. If they are separated then the target is free to choose resolvers, and just act as a go-between. The only real requirement, remember, is that the proxy and target never collude.

Also, importantly, clients are in complete control of proxy and target selection. Without any need for TRR-like programs, clients can have privacy for their queries, in addition to security. Since the target only knows about the proxy, the target and any upstream resolver are oblivious to the existence of any client IP addresses. Importantly, this puts clients in greater control over their queries and the ways they might be used. For example, clients could select and alter their proxies and targets any time, for any reason!

ODoH Message Flow

In ODoH, the ‘O’ stands for oblivious, and this property comes from the level of encryption of the DNS messages themselves. This added encryption is `end-to-end` between client and target, and independent from the connection-level encryption provided by TLS/HTTPS. One might ask why this additional encryption is required at all in the presence of a proxy. This is because two separate TLS connections are required to support proxy functionality. Specifically, the proxy terminates a TLS connection from the client, and initiates another TLS connection to the target. Between those two connections, the DNS message contexts would otherwise appear in plaintext! For this reason, ODoH additionally encrypts messages between client and target so the proxy has no access to the message contents.

The whole process begins with clients that encrypt their query for the target using HPKE. Clients obtain the target’s public key via DNS, where it is bundled into a HTTPS resource record and protected by DNSSEC. When the TTL for this key expires, clients request a new copy of the key as needed (just as they would for an A/AAAA record when that record’s TTL expires). The usage of a target’s DNSSEC-validated public key guarantees that only the intended target can decrypt the query and encrypt a response (answer).

Clients transmit these encrypted queries to a proxy over an HTTPS connection. Upon receipt, the proxy forwards the query to the designated target. The target then decrypts the query, produces a response by sending the query to a recursive resolver such as 1.1.1.1, and then encrypts the response to the client. The encrypted query from the client contains encapsulated keying material from which targets derive the response encryption symmetric key.

This response is then sent back to the proxy, and then subsequently forwarded to the client. All communication is authenticated and confidential since these DNS messages are end-to-end encrypted, despite being transmitted over two separate HTTPS connections (client-proxy and proxy-target). The message that otherwise appears to the proxy as plaintext is actually an encrypted garble.

What about Performance? Do I have to trade performance to get privacy?

We’ve been doing lots of measurements to find out, and will be doing more as ODoH deploys more widely. Our initial set of measurement configurations spanned cities in the USA, Canada, and Brazil. Importantly, our measurements include not just 1.1.1.1, but also 8.8.8.8 and 9.9.9.9. The full set of measurements, so far, is documented for open access.

In those measurements, it was important to isolate the cost of proxying and additional encryption from the cost of TCP and TLS connection setup. This is because the TLS and TCP costs are incurred by DoH, anyway. So, in our setup, we ‘primed’ measurements by establishing connections once and reusing that connection for all measurements. We did this for both DoH and for ODoH, since the same strategy could be used in either case.

The first thing that we can say with confidence is that the additional encryption is marginal. We know this because we randomly selected 10,000 domains from the Tranco million dataset and measured both encryption of the A record with a different public key, as well as its decryption. The additional cost between a proxied DoH query/response and its ODoH counterpart is consistently less than 1ms at the 99th percentile.

The ODoH request-response pipeline, however, is much more than just encryption. A very useful way of looking at measurements is by looking at the cumulative distribution chart — if you’re familiar with these kinds of charts, skip to the next paragraph. In contrast to most charts where we start along the x-axis, with cumulative distributions we often start with the y-axis.

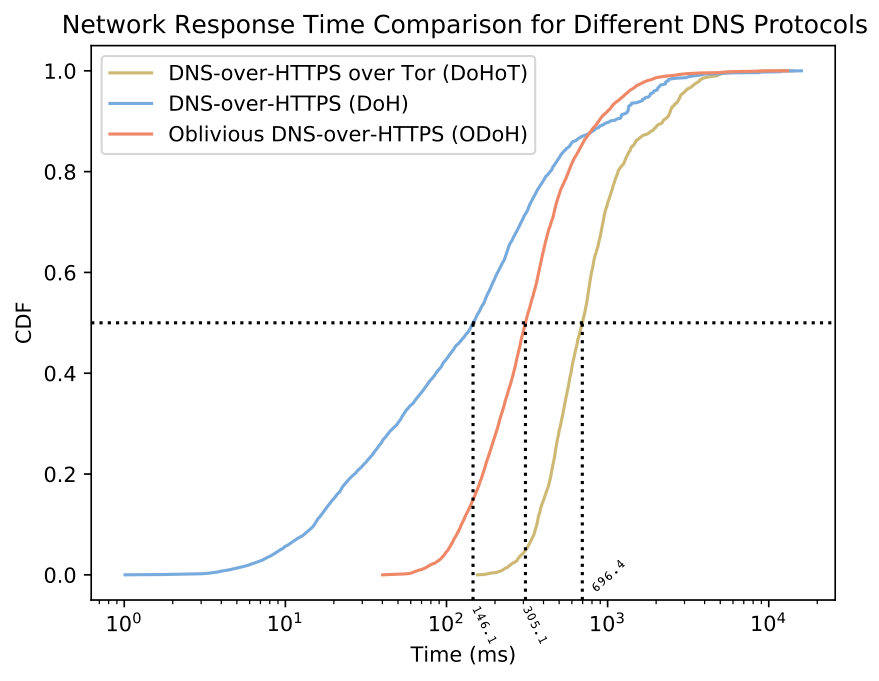
The chart below shows the cumulative distributions for query/response times in DoH, ODoH, and DoH when transmitted over the Tor Network. The dashed horizontal line that starts on the left from 0.5 is the 50% mark. Along this horizontal line, for any plotted curve, the part of the curve below the dashed line is 50% of the data points. Now look at the x-axis, which is a measure of time. The lines that appear to the left are faster than lines to the right. One last important detail is that the x-axis is plotted on a logarithmic scale. What does this mean? Notice that the distance between the labeled markers (10x) is equal in cumulative distributions but the ‘x’ is an exponent, and represents orders of magnitude. So, while the time difference between the first two markers is 9ms, the difference between the 3rd and 4th markers is 900ms.

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

In this chart, the middle curve represents ODoH measurements. We also measured the performance of privacy-preserving alternatives, for example, DoH queries transmitted over the Tor network as represented by the right curve in the chart. (Additional privacy-preserving alternatives are captured in the open access technical report.) Compared to other privacy-oriented DNS variants, ODoH cuts query time in half, or better. This point is important since privacy and performance rarely play nicely together, so seeing this kind of improvement is encouraging!

The chart above also tells us that 50% of the time ODoH queries are resolved in fewer than 228ms. Now compare the middle line to the left line that represents ‘straight-line’ (or normal) DoH without any modification. That left plotline says that 50% of the time, DoH queries are resolved in fewer than 146ms. Looking below the 50% mark, the curves also tell us that ½ the time that difference is never greater than 100ms. On the other side, looking at the curves above the 50% mark tells us that ½ ODoH queries are competitive with DoH.

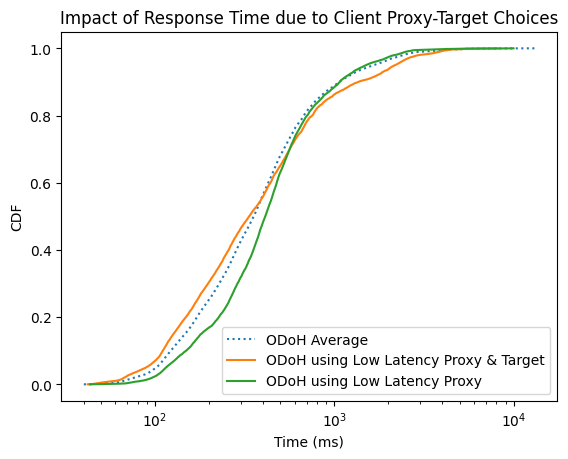
Those curves also hide a lot of information, so it is important to delve further into the measurements. The chart below has three different cumulative distribution curves that describe ODoH performance if we select proxies and targets by their latency. This is also an example of the insights that measurements can reveal, some of which are counterintuitive. For example, looking above 0.5, these curves say that ½ of ODoH query/response times are virtually indistinguishable, no matter the choice of proxy and target. Now shift attention below 0.5 and compare the two solid curves against the dashed curve that represents overall average. This region suggests that selecting the lowest-latency proxy and target offers minimal improvement over the average but, most importantly, it shows that selecting the lowest-latency proxy leads to worse performance!

Improving DNS Privacy with Oblivious DoH in 1.1.1.1

Open questions remain, of course. This first set of measurements were executed largely in North America. Does performance change at a global level? How does this affect client performance, in practice? We’re working on finding out, and this release will help us to do that.

Interesting! Can I experiment with ODoH? Is there an open ODoH service?

Yes, and yes! We have open sourced our interoperable ODoH implementations in Rust, odoh-rs and Go, odoh-go, as well as integrated the target into the Cloudflare DNS Resolver. That’s right, 1.1.1.1 is ready to receive queries via ODoH.

We have also open sourced test clients in Rust, odoh-client-rs, and Go, odoh-client-go, to demo ODoH queries. You can also check out the HPKE configuration used by ODoH for message encryption to 1.1.1.1 by querying the service directly:

$ dig -t type65 +dnssec @ns1.cloudflare.com odoh.cloudflare-dns.com 

; <<>> DiG 9.10.6 <<>> -t type65 +dnssec @ns1.cloudflare.com odoh.cloudflare-dns.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 19923
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available

;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags: do; udp: 1232
;; QUESTION SECTION:
;odoh.cloudflare-dns.com.	IN	TYPE65

;; ANSWER SECTION:
odoh.cloudflare-dns.com. 300	IN	TYPE65	\# 108 00010000010003026832000400086810F8F96810F9F9000600202606 470000000000000000006810F8F92606470000000000000000006810 F9F98001002E002CFF0200280020000100010020ED82DBE32CCDE189 BC6C643A80B5FAFF82548D21601C613408BACAAE6467B30A
odoh.cloudflare-dns.com. 300	IN	RRSIG	TYPE65 13 3 300 20201119163629 20201117143629 34505 odoh.cloudflare-dns.com. yny5+ApxPSO6Q4aegv09ZnBmPiXxDEnX5Xv21TAchxbxt1VhqlHpb5Oc 8yQPNGXb0fb+NyibmHlvTXjphYjcPA==

;; Query time: 21 msec
;; SERVER: 173.245.58.100#53(173.245.58.100)
;; WHEN: Wed Nov 18 07:36:29 PST 2020
;; MSG SIZE  rcvd: 291

We are working to add ODoH to existing stub resolvers such as cloudflared. If you’re interested in adding support to a client, or if you encounter bugs with the implementations, please drop us a line at [email protected]! Announcements about the ODoH specification and server will be sent to the IETF DPRIVE mailing list. You can subscribe and follow announcements and discussion about the specification here.

We are committed to moving it forward in the IETF and are already seeing interest from client vendors. Eric Rescorla, CTO of Firefox, says, “Oblivious DoH is a great addition to the secure DNS ecosystem. We’re excited to see it starting to take off and are looking forward to experimenting with it in Firefox.” We hope that more operators join us along the way and provide support for the protocol, by running either proxies or targets, and we hope client support will increase as the available infrastructure increases, too.

The ODoH protocol is a practical approach for improving privacy of users, and aims to improve the overall adoption of encrypted DNS protocols without compromising performance and user experience on the Internet.

Acknowledgements

Marek Vavruša and Anbang Wen were instrumental in getting the 1.1.1.1 resolver to support ODoH. Chris Wood and Peter Wu helped get the ODoH libraries ready and tested.

Diversity and inclusion in computing education — new research seminars

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/diversity-inclusion-computing-education-research-seminars/

At the Raspberry Pi Foundation, we host a free online research seminar once a month to explore a wide variety of topics in the area of digital and computing education. This year, we’ve hosted eleven seminars — you can (re)discover slides and recordings on our website.

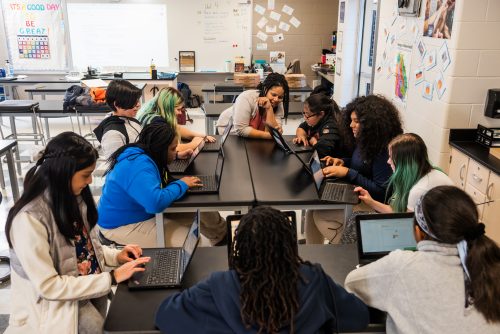
A classroom of young learners and a teacher at laptops

Now we’re getting ready for new seminars in 2021! In the coming months, our seminars are going to focus on diversity and inclusion in computing education. This topic is extremely important, as we want to make sure that computing is accessible to all, that we understand how to actively remove barriers to participation for learners, and that we understand how to teach computing in an inclusive way. 

We are delighted to announce that these seminars focusing on diversity and inclusion will be co-hosted by the Royal Academy of Engineering. The Royal Academy of Engineering is harnessing the power of engineering to build a sustainable society and an inclusive economy that works for everyone.

Royal Academy of Engineering logo

We’re very excited to be partnering with the Academy because of our shared interest in ensuring that computing and engineering are inclusive and accessible to all.

Our upcoming seminars

The seminars take place on the first Tuesday of the month at 17:00–18:30 GMT / 12:00–13:30 EST / 9:00–10:30 PST / 18:00–19:30 CET.

  • 5 January 2021: Peter Kemp (King’s College London) and Billy Wong (University of Reading) will be looking at computing education in England, particularly GCSE computer science, and how it is accessed by groups typically underrepresented in computing.
  • 2 February 2021: Professor Tia Madkins (University of Texas at Austin), Nicol R. Howard (University of Redlands), and Shomari Jones (Bellevue School District) will be talking about equity-focused teaching in K–12 computer science. Find out more.
  • 2 March 2021: Dr Jakita O. Thomas (Auburn University, Alabama) will be talking about her research on supporting computational algorithmic thinking in the context of intersectional computing.
  • April 2021: event to be confirmed
  • 4 May 2021: Dr Cecily Morrison (Microsoft Research) will be speaking about her work on physical programming for people with visual impairments.

Join the seminars

We’d love to welcome you to these seminars so we can learn and discuss together. To get access, simply sign up with your name and email address.

Once you’ve signed up, we’ll email you the seminar meeting link and instructions for joining. If you attended our seminars in the past, the link remains the same.

The post Diversity and inclusion in computing education — new research seminars appeared first on Raspberry Pi.

PRIMM: encouraging talk in programming lessons

Post Syndicated from Oliver Quinlan original https://www.raspberrypi.org/blog/primm-talk-in-programming-lessons-research-seminar/

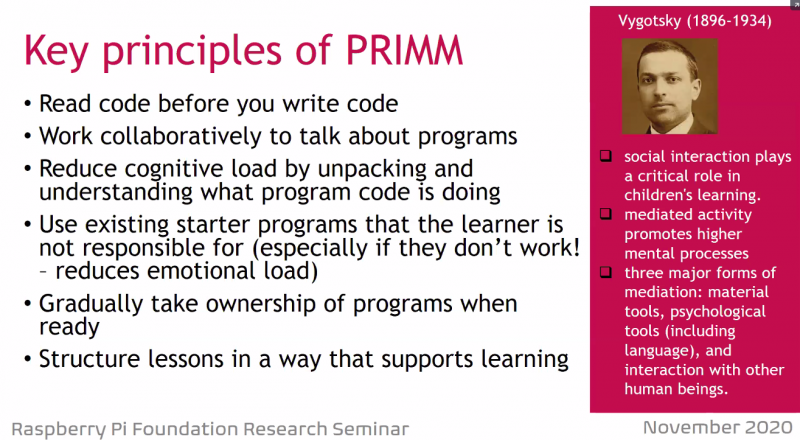
Whenever you learn a new subject or skill, at some point you need to pick up the particular language that goes with that domain. And the only way to really feel comfortable with this language is to practice using it. It’s exactly the same when learning programming.

A girl doing Scratch coding in a Code Club classroom

In our latest research seminar, we focused on how we educators and our students can talk about programming. The seminar presentation was given by our Chief Learning Officer, Dr Sue Sentance. She shared the work she and her collaborators have done to develop a research-based approach to teaching programming called PRIMM, and to work with teachers to investigate the effects of PRIMM on students.

Sue Sentance

As well as providing a structure for programming lessons, Sue’s research on PRIMM helps us think about ways in which learners can investigate programs, start to understand how they work, and then gradually develop the language to talk about them themselves.

Productive talk for education

Sue began by taking us through the rich history of educational research into language and dialogue. This work has been heavily developed in science and mathematics education, as well as language and literacy.

In particular the work of Neil Mercer and colleagues has shown that students need guidance to develop and practice using language to reason, and that developing high-quality language improves understanding. The role of the teacher in this language development is vital.

Sue’s work draws on these insights to consider how language can be used to develop understanding in programming.

Why is programming challenging for beginners?

Sue identified shortcomings of some teaching approaches that are common in the computing classroom but may not be suitable for all beginners.

  • ‘Copy code’ activities for learners take a long time, lead to dreaded syntax errors, and don’t necessarily build more understanding.
  • When teachers model the process of writing a program, this can be very helpful, but for beginners there may still be a huge jump from being able to follow the modeling to being able to write a program from scratch themselves.

PRIMM was designed by Sue and her collaborators as a language-first approach where students begin not by writing code, but by reading it.

What is PRIMM?

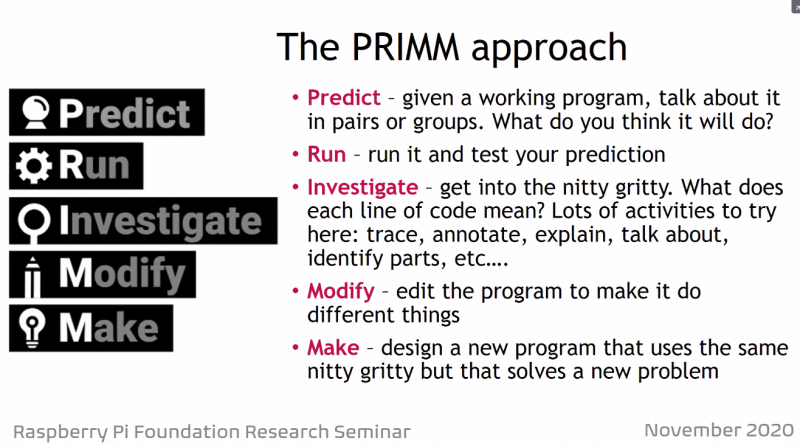
PRIMM stands for ‘Predict, Run, Investigate, Modify, Make’. In this approach, rather than copying code or writing programs from scratch, beginners instead start by focussing on reading working code.

In the Predict stage, the teacher provides learners with example code to read, discuss, and make output predictions about. Next, they run the code to see how the output compares to what they predicted. In the Investigate stage, the teacher sets activities for the learners to trace, annotate, explain, and talk about the code line by line, in order to help them understand what it does in detail.

In the seminar, Sue took us through a mini example of the stages of PRIMM where we predicted the output of Python Turtle code. You can follow along on the recording of the seminar to get the experience of what it feels like to work through this approach.

The impact of PRIMM on learning

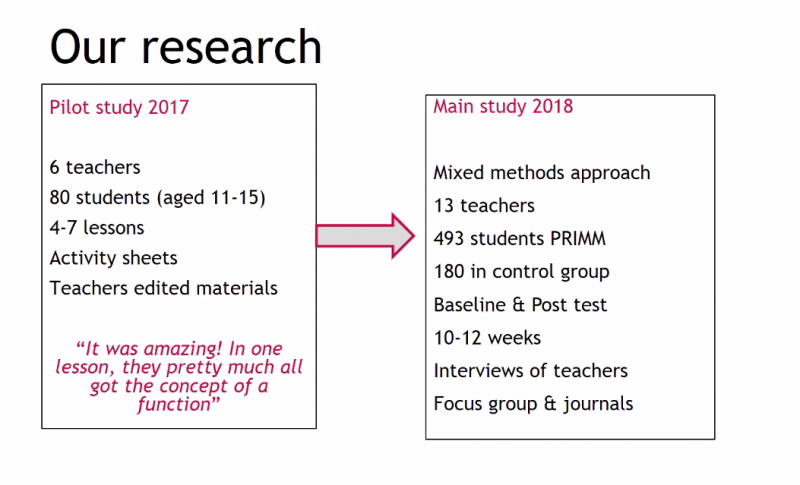
The PRIMM approach is informed by research, and it is also the subject of research by Sue and her collaborators. They’ve conducted two studies to measure the effectiveness of PRIMM: an initial pilot, and a larger mixed-methods study with 13 teachers and 493 students with a control group.

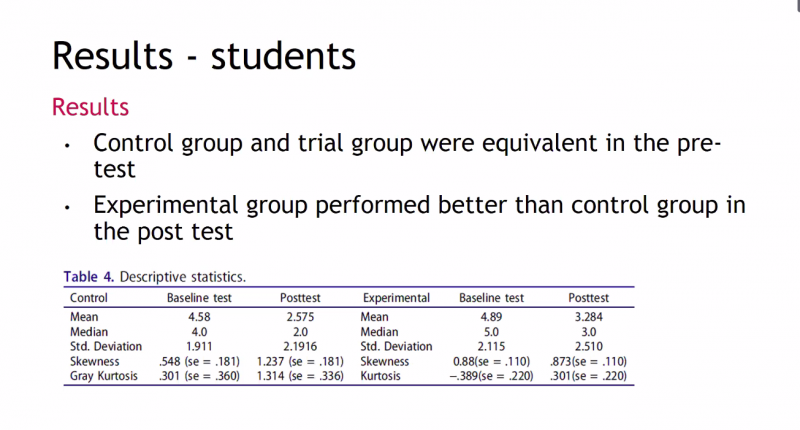
The larger study used a pre and post test, and found that the group who experienced a PRIMM approach performed better on the tests than the control group. The researchers also collected a wealth of qualitative feedback from teachers. The feedback suggested that the approach can help students to develop a language to express their understanding of programming, and that there was much more productive peer conversation in the PRIMM lessons (sometimes this meant less talk, but at a more advanced level).

The PRIMM structure also gave some teachers a greater capacity to talk about the process of teaching programming. It facilitated the discussion of teaching ideas and learning approaches for the teachers, as well as developing language approaches that students used to learn programming concepts.

The research results suggest that learners taught using PRIMM appear to be developing the language skills to talk coherently about their programming. The effectiveness of PRIMM is also evidenced by the number of teachers who have taken up the approach, building in their own activities and in some cases remixing the PRIMM terminology to develop their own take on a language-first approach to teaching programming.

Future research will investigate in detail how PRIMM encourages productive talk in the classroom, and will link the approach to other work on semantic waves. (For more on semantic waves in computing education, see this seminar by Jane Waite and this symposium talk by Paul Curzon.)

Resources for educators who want to try PRIMM

If you would like to try out PRIMM with your learners, use our free support materials:

Join our next seminar

If you missed the seminar, you can find the presentation slides alongside the recording of Sue’s talk on our seminars page.

In our next seminar on Tuesday 1 December at 17:00–18:30 GMT / 12:00–13:30 EsT / 9:00–10:30 PT / 18:00–19:30 CEST. Dr David Weintrop from the University of Maryland will be presenting on the role of block-based programming in computer science education. To join, simply sign up with your name and email address.

Once you’ve signed up, we’ll email you the seminar meeting link and instructions for joining. If you attended this past seminar, the link remains the same.

The post PRIMM: encouraging talk in programming lessons appeared first on Raspberry Pi.

Formative assessment in the computer science classroom

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/research-seminar-formative-assessment-computer-science-classroom/

In computing education research, considerable focus has been put on the design of teaching materials and learning resources, and investigating how young people learn computing concepts. But there has been less focus on assessment, particularly assessment for learning, which is called formative assessment. As classroom teachers are engaged in assessment activities all the time, it’s pretty strange that researchers in the area of computing and computer science in school have not put a lot of focus on this.

Shuchi Grover

That’s why in our most recent seminar, we were delighted to hear about formative assessment — assessment for learning — from Dr Shuchi Grover, of Looking Glass Ventures and Stanford University in the USA. Shuchi has a long track record of work in the learning sciences (called education research in the UK), and her contribution in the area of computational thinking has been hugely influential and widely drawn on in subsequent research.

Two types of assessment

Assessment is typically divided into two types:

  1. Summative assessment (i.e. assessing what has been learned), which typically takes place through examinations, final coursework, projects, etcetera.
  2. Formative assessment (i.e. assessment for learning), which is not aimed at giving grades and typically takes place through questioning, observation, plenary classroom activities, and dialogue with students.

Through formative assessment, teachers seek to find out where students are at, in order to use that information both to direct their preparation for the next teaching activities and to give students useful feedback to help them progress. Formative assessment can be used to surface misconceptions (or alternate conceptions) and for diagnosis of student difficulties.

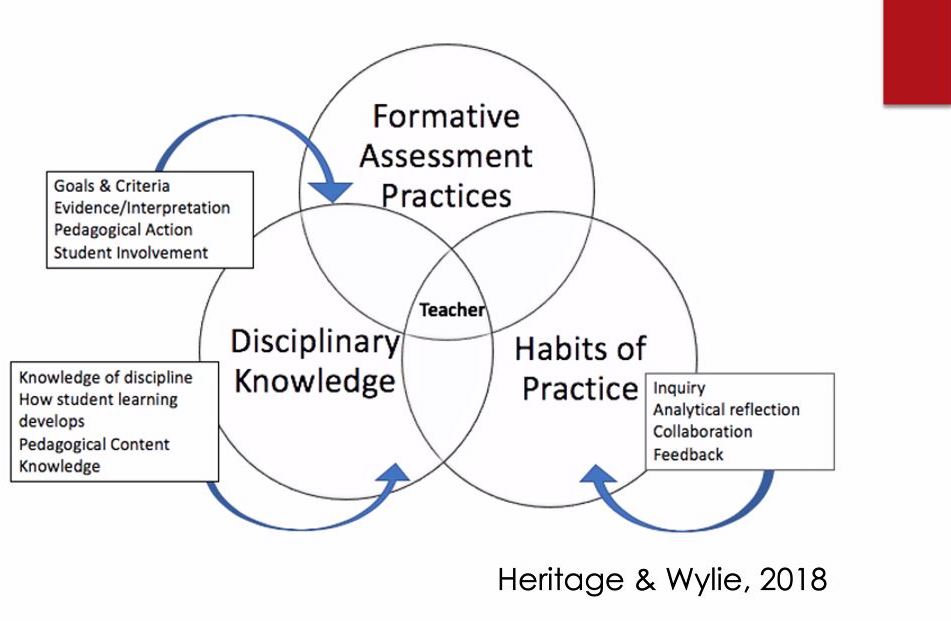
Venn diagram of how formative assessment practices intersect with teacher knowledge and skills
Click to enlarge

As Shuchi outlined in her talk, a variety of activities can be used for formative assessment, for example:

  • Self- and peer-assessment activities (commonly used in schools).
  • Different forms of questioning and quizzes to support learning (not graded tests).
  • Rubrics and self-explanations (for assessing projects).

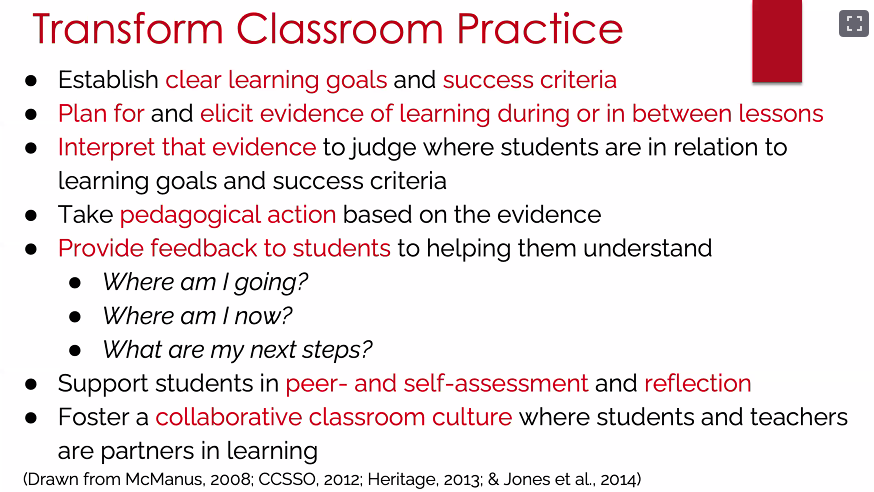
A framework for formative assessment

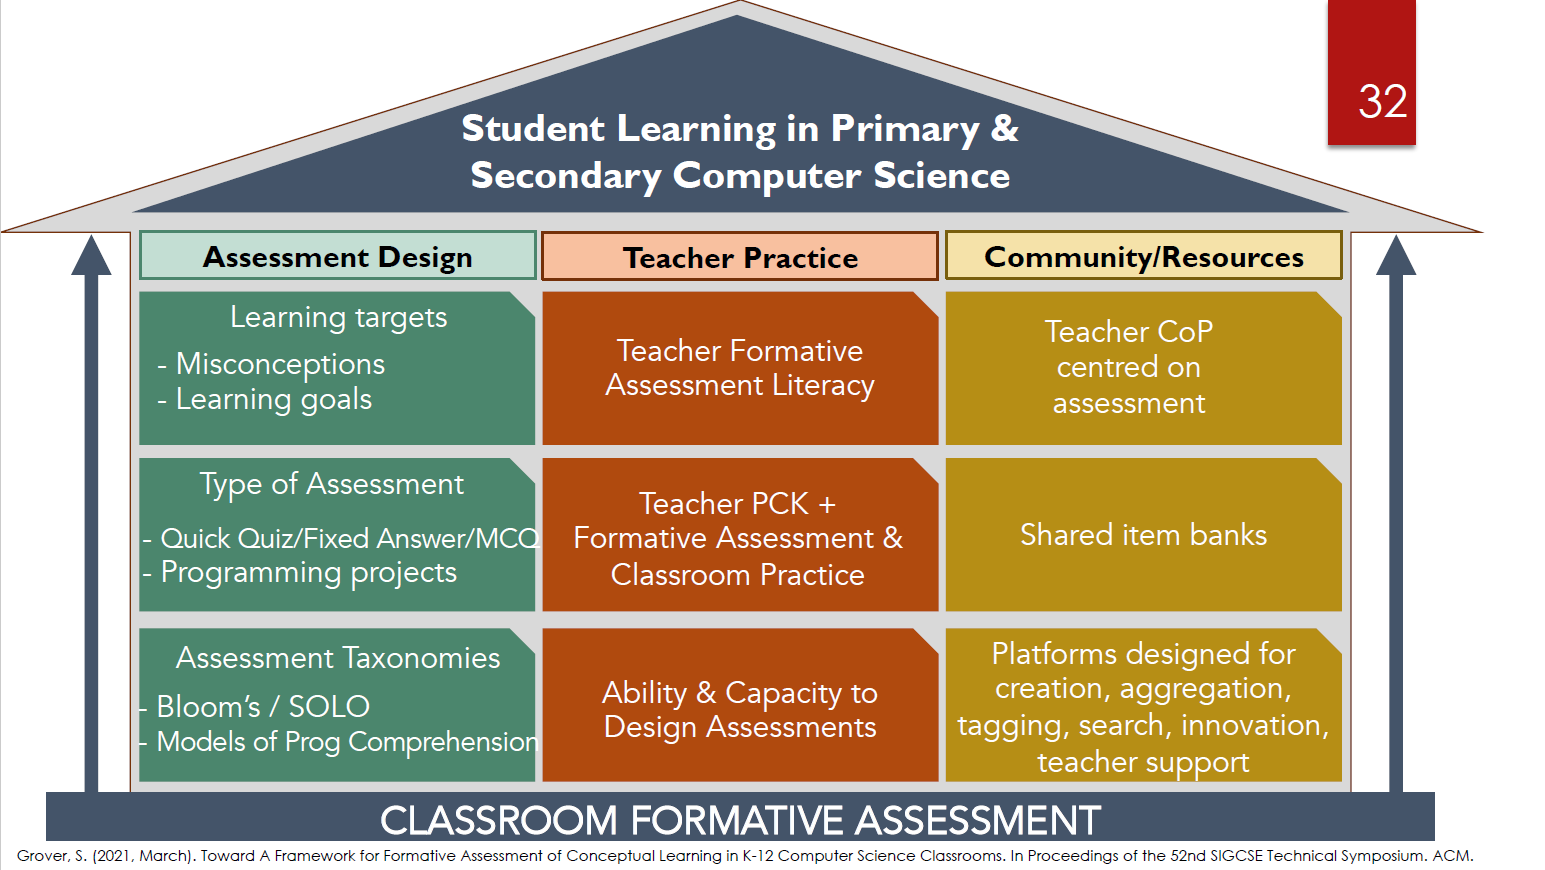
Shuchi described her own research in this topic, including a framework she has developed for formative assessment. This comprises three pillars:

  1. Assessment design.
  2. Teacher or classroom practice.
  3. The role of the community in furthering assessment practice.
Shuchi Grover's framework for formative assessment
Click to enlarge

Shuchi’s presentation then focused on part of the first pillar in the framework: types of assessments, and particularly types of multiple-choice questions that can be automatically marked or graded using software tools. Tools obviously don’t replace teachers, but they can be really useful for providing timely and short-turnaround feedback for students.

As part of formative assessment, carefully chosen questions can also be used to reveal students’ misconceptions about the subject matter — these are called diagnostic questions. Shuchi discussed how in a classroom setting, teachers can employ this kind of question to help them decide what to focus on in future lessons, and to understand their students’ alternate or different conceptions of a topic. 

Formative assessment of programming skills

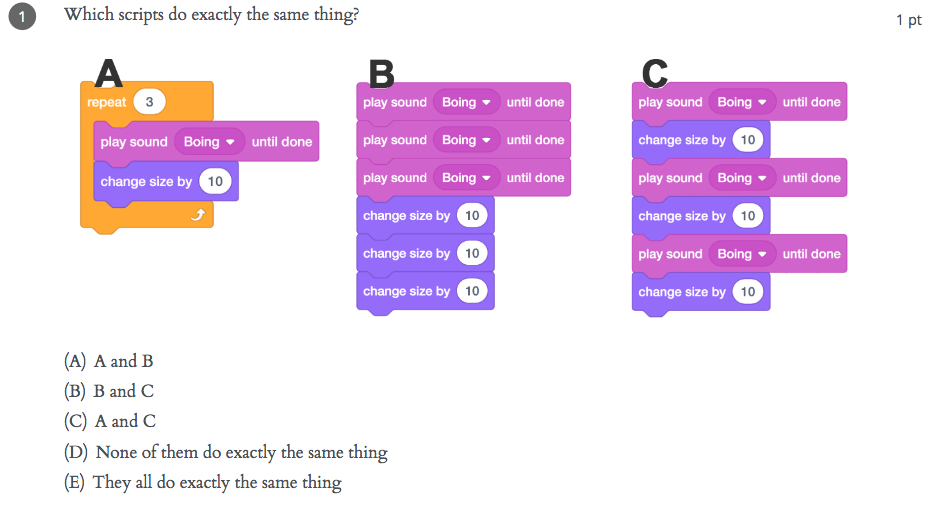
The remainder of the seminar focused on the formative assessment of programming skills. There are many ways of assessing developing programming skills (see Shuchi’s slides), including Parsons problems, microworlds, hotspot items, rubrics (for artifacts), and multiple-choice questions. As an MCQ example, in the figure below you can see some snippets of block-based code, which students need to read and work out what the outcome of running the snippets will be. 

Click to enlarge

Questions such as this highlight that it’s important for learners to engage in code comprehension and code reading activities when learning to program. This really underlines the fact that such assessment exercises can be used to support learning just as much as to monitor progress.

Formative assessment: our support for teachers

Interestingly, Shuchi commented that in her experience, teachers in the UK are more used to using code reading activities than US teachers. This may be because code comprehension activities are embedded into the curriculum materials and support for pedagogy, both of which the Raspberry Pi Foundation developed as part of the National Centre for Computing Education in England. We explicitly share approaches to teaching programming that incorporate code reading, for example the PRIMM approach. Moreover, our work in the Raspberry Pi Foundation includes the Isaac Computer Science online learning platform for A level computer science students and teachers, which is centered around different types of questions designed as tools for learning.

All these materials are freely available to teachers wherever they are based.

Further work on formative assessment

Based on her work in US classrooms researching this topic, Shuchi’s call to action for teachers was to pay attention to formative assessment in computer science classrooms and to investigate what useful tools can support them to give feedback to students about their learning. 

Advice from Shuchi Grover on how to embed formative assessment in classroom practice
Click to enlarge

Shuchi is currently involved in an NSF-funded research project called CS Assess to further develop formative assessment in computer science via a community of educators. For further reading, there are two chapters related to formative assessment in computer science classrooms in the recently published book Computer Science in K-12 edited by Shuchi.

There was much to take away from this seminar, and we are really grateful to Shuchi for her input and look forward to hearing more about her developing project.

Join our next seminar

If you missed the seminar, you can find the presentation slides and a recording of the Shuchi’s talk on our seminars page.

In our next seminar on Tuesday 3 November at 17:00–18:30 BST / 12:00–13:30 EDT / 9:00–10:30 PT / 18:00–19:30 CEST, I will be presenting my work on PRIMM, particularly focusing on language and talk in programming lessons. To join, simply sign up with your name and email address.

Once you’ve signed up, we’ll email you the seminar meeting link and instructions for joining. If you attended this past seminar, the link remains the same.

The post Formative assessment in the computer science classroom appeared first on Raspberry Pi.

Embedding computational thinking skills in our learning resources

Post Syndicated from Oliver Quinlan original https://www.raspberrypi.org/blog/computational-thinking-skills-in-our-free-learning-resources/

Learning computing is fun, creative, and exploratory. It also involves understanding some powerful ideas about how computers work and gaining key skills for solving problems using computers. These ideas and skills are collected under the umbrella term ‘computational thinking’.

When we create our online learning projects for young people, we think as much about how to get across these powerful computational thinking concepts as we do about making the projects fun and engaging. To help us do this, we have put together a computational thinking framework, which you can read right now.

What is computational thinking? A brief summary

Computational thinking is a set of ideas and skills that people can use to design systems that can be run on a computer. In our view, computational thinking comprises:

  • Decomposition
  • Algorithms
  • Patterns and generalisations
  • Abstraction
  • Evaluation
  • Data

All of these aspects are underpinned by logical thinking, the foundation of computational thinking.

What does computational thinking look like in practice?

In principle, the processes a computer performs can also be carried out by people. (To demonstrate this, computing educators have created a lot of ‘unplugged’ activities in which learners enact processes like computers do.) However, when we implement processes so that they can be run on a computer, we benefit from the huge processing power that computers can marshall to do certain types of activities.

A group of young people and educators smiling while engaging with a computer

Computers need instructions that are designed in very particular ways. Computational thinking includes the set of skills we use to design instructions computers can carry out. This skill set represents the ways we can logically approach problem solving; as computers can only solve problems using logical processes, to write programs that run on a computer, we need to use logical thinking approaches. For example, writing a computer program often requires the task the program revolves around to be broken down into smaller tasks that a computer can work through sequentially or in parallel. This approach, called decomposition, can also help people to think more clearly about computing problems: breaking down a problem into its constituent parts helps us understand the problem better.

Male teacher and male students at a computer

Understanding computational thinking supports people to take advantage of the way computers work to solve problems. Computers can run processes repeatedly and at amazing speeds. They can perform repetitive tasks that take a long time, or they can monitor states until conditions are met before performing a task. While computers sometimes appear to make decisions, they can only select from a range of pre-defined options. Designing systems that involve repetition and selection is another way of using computational thinking in practice.

Our computational thinking framework

Our team has been thinking about our approach to computational thinking for some time, and we have just published the framework we have developed to help us with this. It sets out the key areas of computational thinking, and then breaks these down into themes and learning objectives, which we build into our online projects and learning resources.

To develop this computational thinking framework, we worked with a group of academics and educators to make sure it is robust and useful for teaching and learning. The framework was also influenced by work from organisations such as Computing At School (CAS) in the UK, and the Computer Science Teachers’ Association (CSTA) in the USA.

We’ve been using the computational thinking framework to help us make sure we are building opportunities to learn about computational thinking into our learning resources. This framework is a first iteration, which we will review and revise based on experience and feedback.

We’re always keen to hear feedback from you in the community about how we shape our learning resources, so do let us know what you think about them and the framework in the comments.

The post Embedding computational thinking skills in our learning resources appeared first on Raspberry Pi.

How is computing taught in schools around the world?

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/international-computing-curriculum-metrecc-research-seminar/

Around the world, formal education systems are bringing computing knowledge to learners. But what exactly is set down in different countries’ computing curricula, and what are classroom educators teaching? This was the topic of the first in the autumn series of our Raspberry Pi research seminars on Tuesday 8 September.

A glowing globe floating above an open hand in the dark

We heard from an international team (Monica McGill , USA; Rebecca Vivian, Australia; Elizabeth Cole, Scotland) who represented a group of researchers also based in England, Malta, Ireland, and Italy. As a researcher working at the Raspberry Pi Foundation, I myself was part of this research group. The group developed METRECC, a comprehensive and validated survey tool that can be used to benchmark and measure developments of the teaching and learning of computing in formal education systems around the world. Monica, Rebecca, and Elizabeth presented how the research group developed and validated the METRECC tool, and shared some findings from their pilot study.

What’s in a curriculum? Developing a survey tool

Those of us who work or have worked in school education use the word ‘curriculum’ frequently, although it’s an example of education terminology that means different things in different contexts, and to different people. Following Porter and Smithson (2001)1, we can distinguish between the intended curriculum and the enacted curriculum:

  • Intended curriculum: Policy tools as curriculum standards, frameworks, or guidelines that outline the curriculum teachers are expected to deliver.
  • Enacted curriculum: Actual curricular content in which students engage in the classroom, and adopted pedagogical approaches; for computer science (CS) curricula, this also includes students’ use of technology, physical computing devices, and tools in CS lessons.

To compare the intended and enacted computing curriculum in as many countries as possible, at particular points in time, the research group Monica, Rebecca, Elizabeth, and I were part of developed the METRECC survey tool.

A classroom of students in North America

METRECC stands for MEasuring TeacheREnacted Computing Curriculum. The METRECC survey has 11 categories of questions and is designed to be completed by computing teachers within 35–40 minutes. Following best practice in research, which calls for standardised research instruments, the research group ensured that the survey produces valid, reliable results (meaning that it works as intended) before using it to gather data.

Using METRECC in a pilot study

In their pilot study, the research group gathered data from 7 countries. The intended curriculum for each country was determined by examining standards and policies in place for each country/state under consideration. Teachers’ answers in the METRECC survey provided the countries’ enacted curricula. (The complete dataset from the pilot study is publicly available at csedresearch.org, a very useful site for CS education researchers where many surveys are shared.)

Two girls coding at a computer under supervision of a female teacher

The researchers then mapped the intended to the enacted curricula to find out whether teachers were actually teaching the topics that were prescribed for them. Overall, the results of the mapping showed that there was a good match between intended and enacted curricula. Examples of mismatches include lower numbers of primary school teachers reporting that they taught visual or symbolic programming, even though the topic did appear on their curriculum.

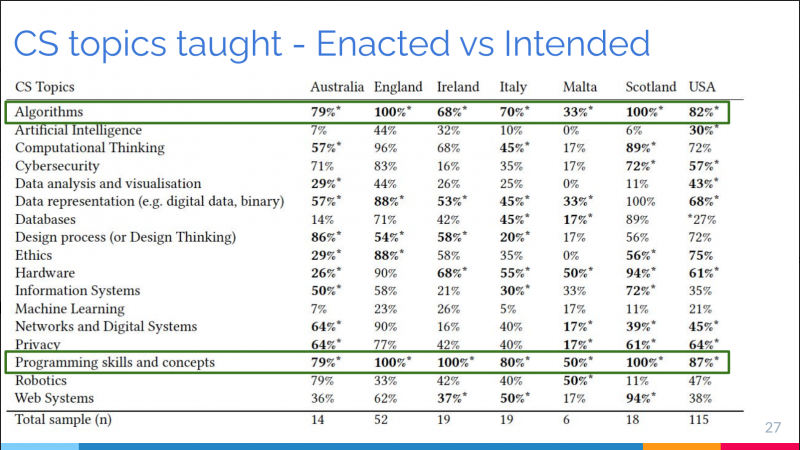
A table listing computer science topics
This table shows computer science topic the METRECC tool asks teachers about, and what percentage of respondents in the pilot study stated that they teach these to their students.

Another aspect of the METRECC survey allows to measure teachers’ confidence, self-efficacy, and self-esteem. The results of the pilot study showed a relationship between years of experience and CS self-esteem; in particular, after four years of teaching, teachers started to report high self-esteem in relation to computer science. Moreover, primary teachers reported significantly lower self-esteem than secondary teachers did, and female teachers reported lower self-esteem than male teachers did.

Adapting the survey’s language

The METRECC survey has also been used in South Asia, namely Bangladesh, Nepal, Pakistan, and Sri Lanka (where computing is taught under ICT). Amongst other things, what the researchers learned from that study was that some of the survey questions needed to be adapted to be relevant to these countries. For example, while in the UK we use the word ‘gifted’ to mean ‘high-attaining’, in the South Asian countries involved in the study, to be ‘gifted’ means having special needs.

Two girls coding at a computer under supervision of a female teacher

The study highlighted how important it is to ensure that surveys intended for an international audience use terminology and references that are pertinent to many countries, or that the survey language is adapted in order to make sense in each context it is delivered. 

Let’s keep this monitoring of computing education moving forward!

The seminar presentation was well received, and because we now hold our seminars for 90 minutes instead of an hour, we had more time for questions and answers.

My three main take-aways from the seminar were:

1. International collaboration is key

It is very valuable to be able to form international working groups of researchers collaborating on a common project; we have so much to learn from each other. Our Raspberry Pi research seminars attract educators and researchers from many different parts of the world, and we can truly push the field’s understanding forward when we listen to experiences and lessons of people from diverse contexts and cultures.

2. Making research data publicly available

Increasingly, it is expected that research datasets are made available in publicly accessible repositories. While this is becoming the norm in healthcare and scientific, it’s not yet as prevalent in computing education research. It was great to be able to publicly share the dataset from the METRECC pilot study, and we encourage other researchers in this field to do the same. 

3. Extending the global scope of this research

Finally, this work is only just beginning. Over the last decade, there has been an increasing move towards teaching aspects of computer science in school in many countries around the world, and being able to measure change and progress is important. Only a handful of countries were involved in the pilot study, and it would be great to see this research extend to more countries, with larger numbers of teachers involved, so that we can really understand the global picture of formal computing education. Budding research students, take heed!

Next up in our seminar series

If you missed the seminar, you can find the presentation slides and a recording of the researchers’ talk on our seminars page.

In our next seminar on Tuesday 6 October at 17:00–18:30 BST / 12:00–13:30 EDT / 9:00–10:30 PT / 18:00–19:30 CEST, we’ll welcome Shuchi Grover, a prominent researcher in the area of computational thinking and formative assessment. The title of Shuchi’s seminar is Assessments to improve student learning in introductory CS classrooms. To join, simply sign up with your name and email address.

Once you’ve signed up, we’ll email you the seminar meeting link and instructions for joining. If you attended this past seminar, the link remains the same.


1. Andrew C. Porter and John L. Smithson. 2001. Defining, Developing and Using Curriculum Indicators. CPRE Research Reports, 12-2001. (2001)

The post How is computing taught in schools around the world? appeared first on Raspberry Pi.