Tag Archives: research seminar

AI literacy begins with data literacy: An example from healthcare

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/ai-literacy-begins-with-data-literacy-an-example-from-healthcare/

The development of AI and data science has transformed how we gain insights from data. In healthcare, AI tools are being used in the development of new treatments as researchers apply machine learning methods to datasets. However, applying AI in healthcare also brings risks, particularly when systems amplify existing biases in data or design.

In our fourth seminar in our current series on teaching about AI in the arts, humanities, and sciences, Kathy Jessen Eller (The Concord Consortium) introduced the Data Science, AI & You (DSAIY) programme, a high school curriculum that helps students critically evaluate the role of data and AI in healthcare.
A picture of Kathy Jessen Eller.
Kathy Jessen Eller (The Concord Consortium)

The role of critical thinking skills in AI education

Kathy began her seminar by arguing that for many students who use AI tools in their coursework, questions remain about whether they are critically evaluating the tools’ outputs. Students may or may not check an AI-generated answer against primary sources to see if the answer is accurate. There is also growing concern that students’ use of AI tools lets them offload cognitive work rather than engage in deeper thinking. This presents a challenge for educators: how do we help students use AI productively while still supporting them to develop the critical judgement needed to evaluate its outputs?

Introducing Data Science, AI & You (DSAIY)

To tackle this challenge, Kathy and her colleagues have developed the Data Science, AI & You (DSAIY) programme (pronounced ‘Daisy’). DSAIY is a semester-long high school curriculum designed to introduce students to AI by actively engaging them in the machine learning process.

The programme introduces machine learning as the engine behind many AI tools, and introduces the concept of bias through real-world examples. Students use a variety of tools to collect and prepare data, train, test, and evaluate models. It culminates in an ‘AI-a-thon’ where young people work in cross-disciplinary teams alongside data scientists, clinicians, and their own teachers to gain real-world experience.
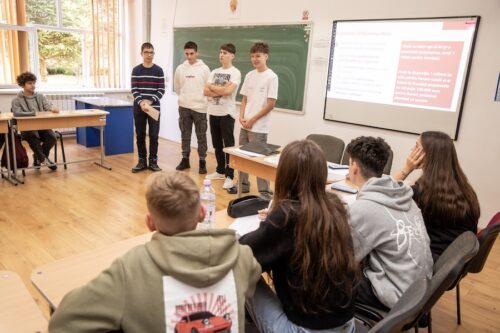
Students in class during an Experience AI lesson.

At the time of the seminar, 11 teachers had delivered the programme to over 800 students across a variety of settings in Rhode Island, USA. Teachers are heavily supported with four days of professional development and ongoing technical assistance throughout implementation. The students that took part had a wide variety of prior experience, including many with no prior background in computer science or statistics. Female participation is notably high; one teacher even remarked that the course saw more girls enrolled than any of his other computer science classes.

Hands-on with machine learning

In DSAIY, students experience the full machine learning pipeline from data collection and data preparation, to modeling and deployment. Using Python, they train and test simple machine learning models on authentic healthcare data. The aim of the programme is to move students from basic graphing to evaluating complex models, transitioning them from merely plotting data to deeply reasoning about it.

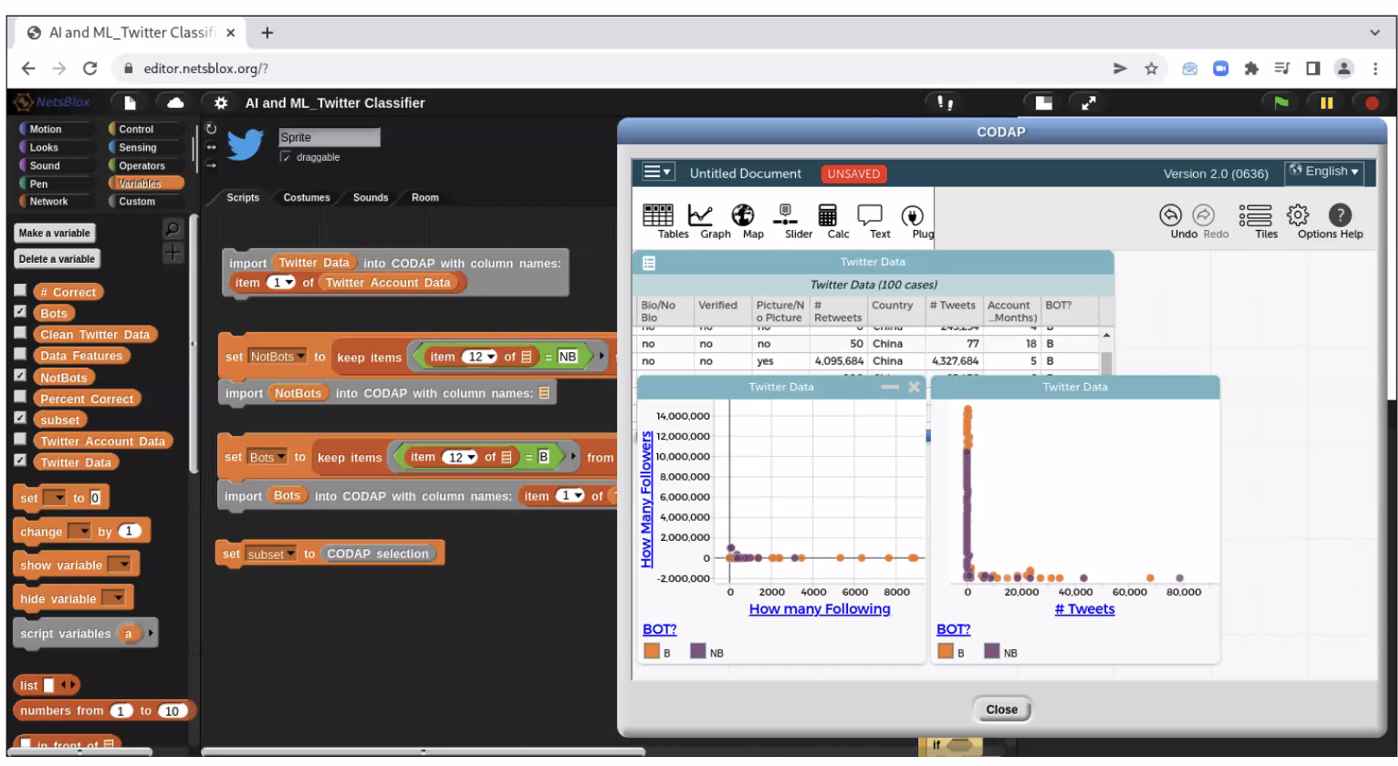
The programme makes use of CODAP (the Common Online Data Analysis Platform), a free, web-based tool developed by The Concord Consortium. CODAP provides an interactive, highly visual environment that lowers the barrier to entry. Students can visualise large datasets and click into individual data points, allowing them to see individual cases within a larger dataset.
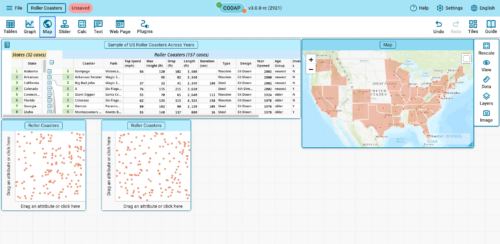
A graphic showing the CODAP tool for data visualisation and analysis.
CODAP, a tool for data visualisation and analysis

Understanding bias in healthcare systems

The curriculum uses real-world examples from healthcare to introduce concepts of bias and fairness. For example, students learn about pulse oximeters, which estimate blood oxygen levels. However, as these use red and infrared light, readings can vary depending on skin pigmentation, which can lead to inaccurate readings.

Students also collect their own blood oxygen data and plot it using CODAP to observe variability. They consider the accuracy of their measurements and grapple with the ethics of removing outliers from a dataset. This led to students asking critical questions about the makeup of their datasets, the context in which data are collected, and the implications of how data are used in healthcare.
Through the DSAIY programme, Kathy reported that students developed stronger data reasoning skills, gained a deeper awareness of inherent AI biases and risks, and built confidence in public speaking and collaborating with others. Students were also highly engaged and appreciated the focus on real-world healthcare applications and their social implications.

The importance of data literacy for AI literacy

Kathy concluded the seminar by arguing that AI literacy must start with data literacy. When students learn to examine, question, and reason about the data behind AI technologies, they develop the critical thinking skills needed to engage with outputs from real-world systems or everyday technologies like ChatGPT. This can then help them evaluate both the trustworthiness of these tools and their role in important decision-making processes.

You can watch the seminar here:

If you are interested in learning more about Kathy’s work, you can read about the DSAIY programme here or you can read the paper here. You can also learn about CODAP, the data visualisation tool featured in this seminar here.

Join our next seminar

In our current seminar series, we’re exploring how AI is taught across the curriculum. In our next seminar on Tuesday 14 July at 17:00–18:30 BST, we welcome Dan Verständig (Goethe University Frankfurt) who will explore the connection between Social explainable AI (Social XAI) and Critical Computational Literacy (CCL). To take part in the seminar, click the button below to register. We hope to see you there.

The schedule of our upcoming seminars is available online. You can catch up on past seminars on our blog and on the previous seminars and recordings page.

The post AI literacy begins with data literacy: An example from healthcare appeared first on Raspberry Pi Foundation.
Do you have some rope? Then let’s teach about AI concepts

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/do-you-have-some-rope-then-lets-teach-about-ai-concepts/

Teaching about AI concepts in schools is a tricky business as there are complicated ideas to be taught.

To teach complex concepts, in computer science, we often use an instructional approach called ‘unplugged’. We use the unplugged approach to teach computing concepts without a computer. Often unplugged activities include using an everyday analogy or a physical fun activity. For example, to teach about algorithms, students might learn how to make a jam sandwich where the recipe and following instructions accurately are similar to an algorithm and the steps within it used to write a program. The jam sandwich activity has now become a popular and key teaching experience for young students across the world, as it teaches a complex but fundamental idea in a simple and fun way.

Salomey Afua Addo is a third-year PhD student at the Raspberry Pi Computing Education Research Centre, University of Cambridge.
Salomey Afua Addo, third-year PhD student at the Raspberry Pi Computing Education Research Centre, University of Cambridge

At the January 2026 Raspberry Pi Foundation Research Seminar, Salomey Afua Addo, a researcher at the University of Cambridge, presented her work about how to teach about AI. She has specifically looked at this in the context of high school students in Ghana, where AI is now part of the mandatory curriculum. In Ghana, most schools do not have access to computers, therefore an unplugged approach to teach about AI is a good idea. Therefore, Salomey developed a set of unplugged activities to teach about a range of AI concepts.

Here, I focus on one of the activities that she presented — one that I think will become another ‘jam sandwich’ experience for students. So if you might teach about AI at some point, then read on.

Neural networks and rope: An unplugged activity

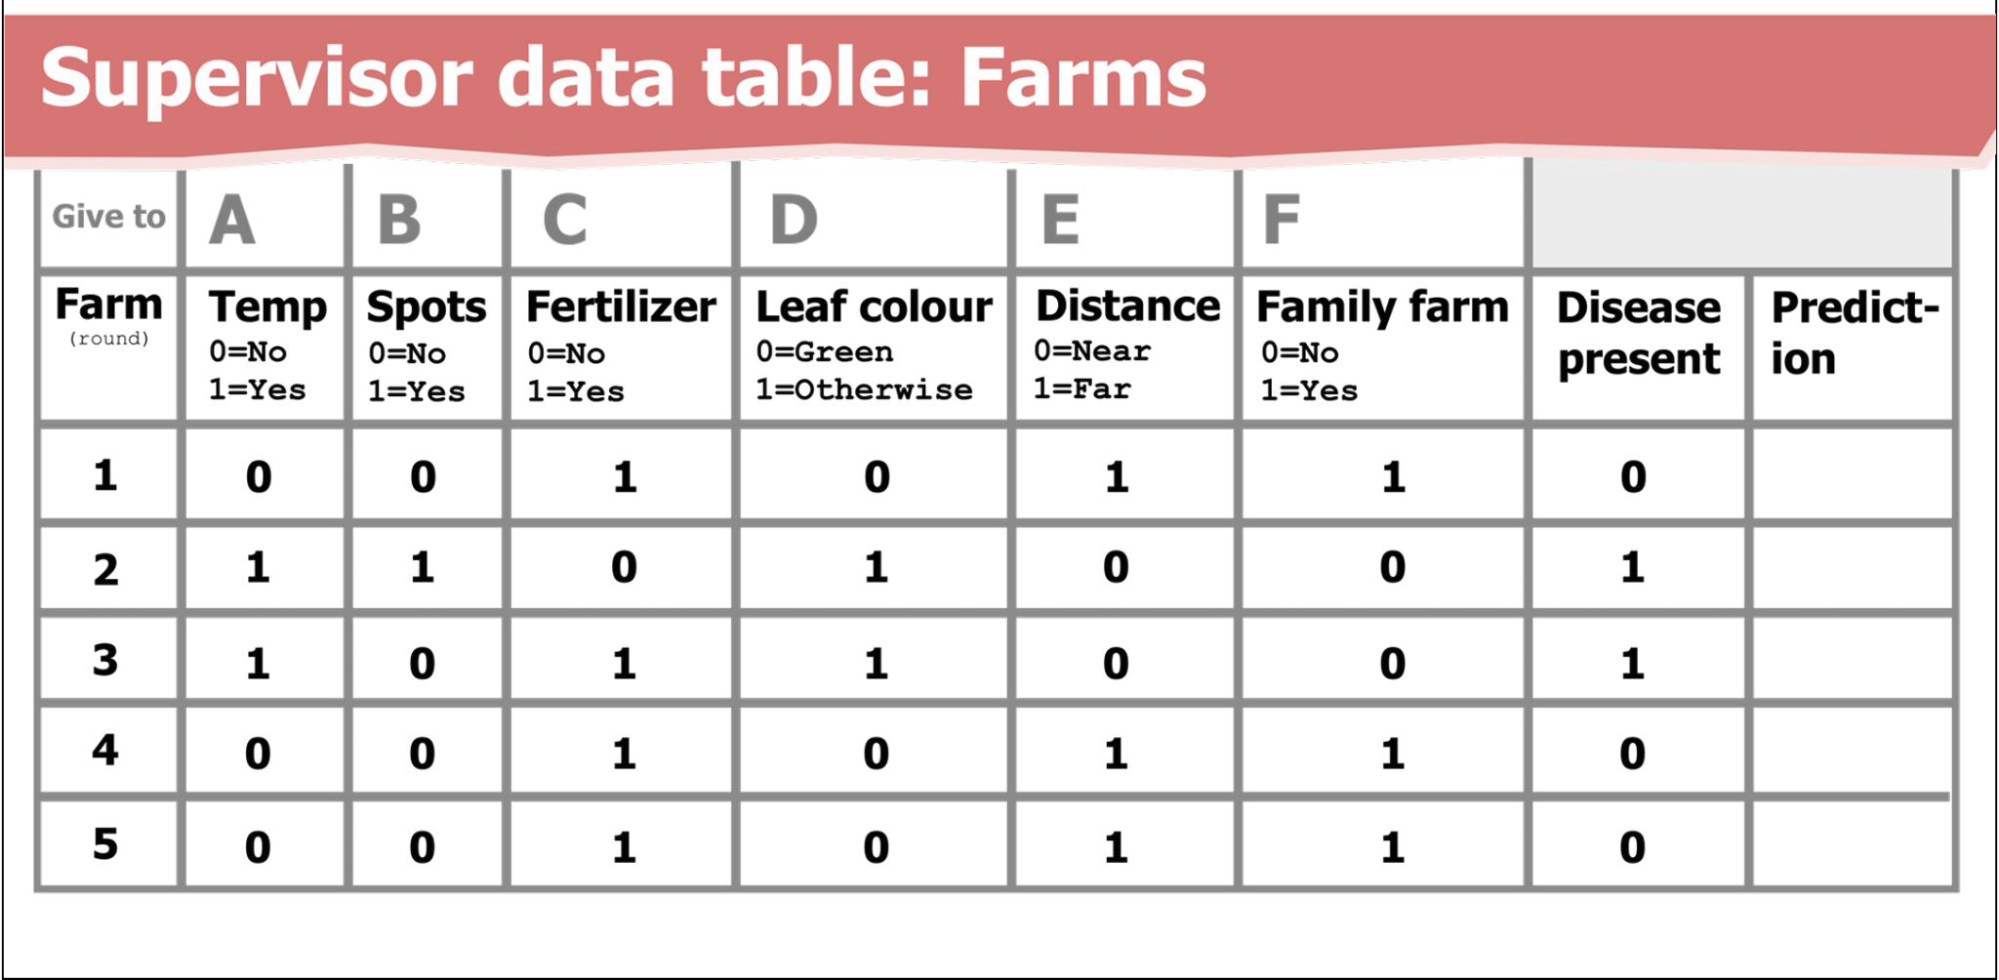
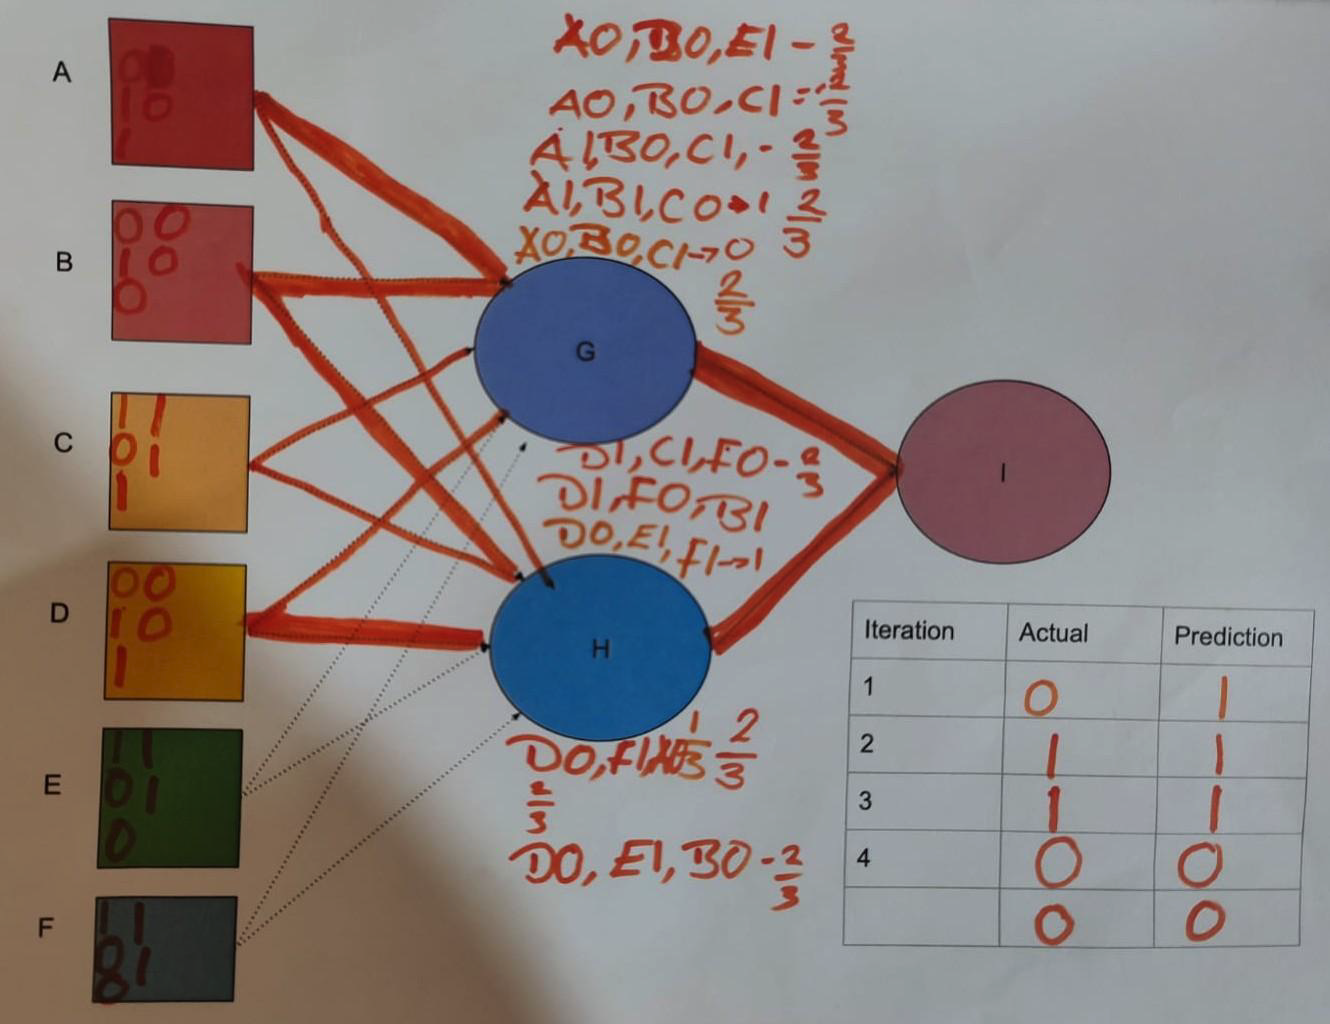
Salomey has designed an unplugged role-play activity to teach about neural networks and how they are trained to solve a problem. She focused on finding a familiar problem context for Ghanaian teachers and their students, and selected farming and crop disease. Students are asked to figure out what features about a farm are relevant for detecting diseases on cocoa trees. To solve the problem, students are given data about the farms (see Table 1). Giving students data, rather than preconceived rules about the context is key to the learning activity. Neural networks are data-driven — they provide a way to model given data so that we can make predictions. Here the features of farms, and importantly whether disease is or is not found in their cocoa trees, is the data that is used to train a model. The model is used to make predictions, which can then be used to improve farming by reducing crop disease. 

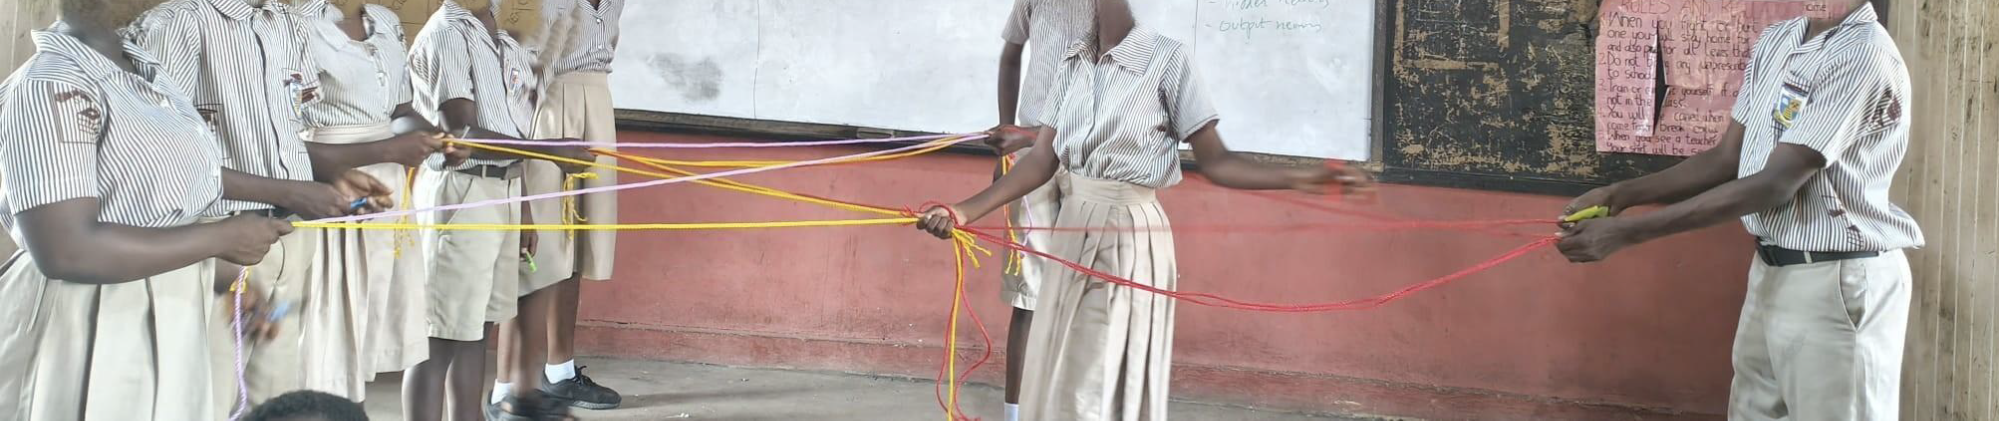
Students using ropes to signify the strength of connections between nodes.

Using farm data, students can learn how neural networks work, and they can do this through an unplugged role play — using ropes!

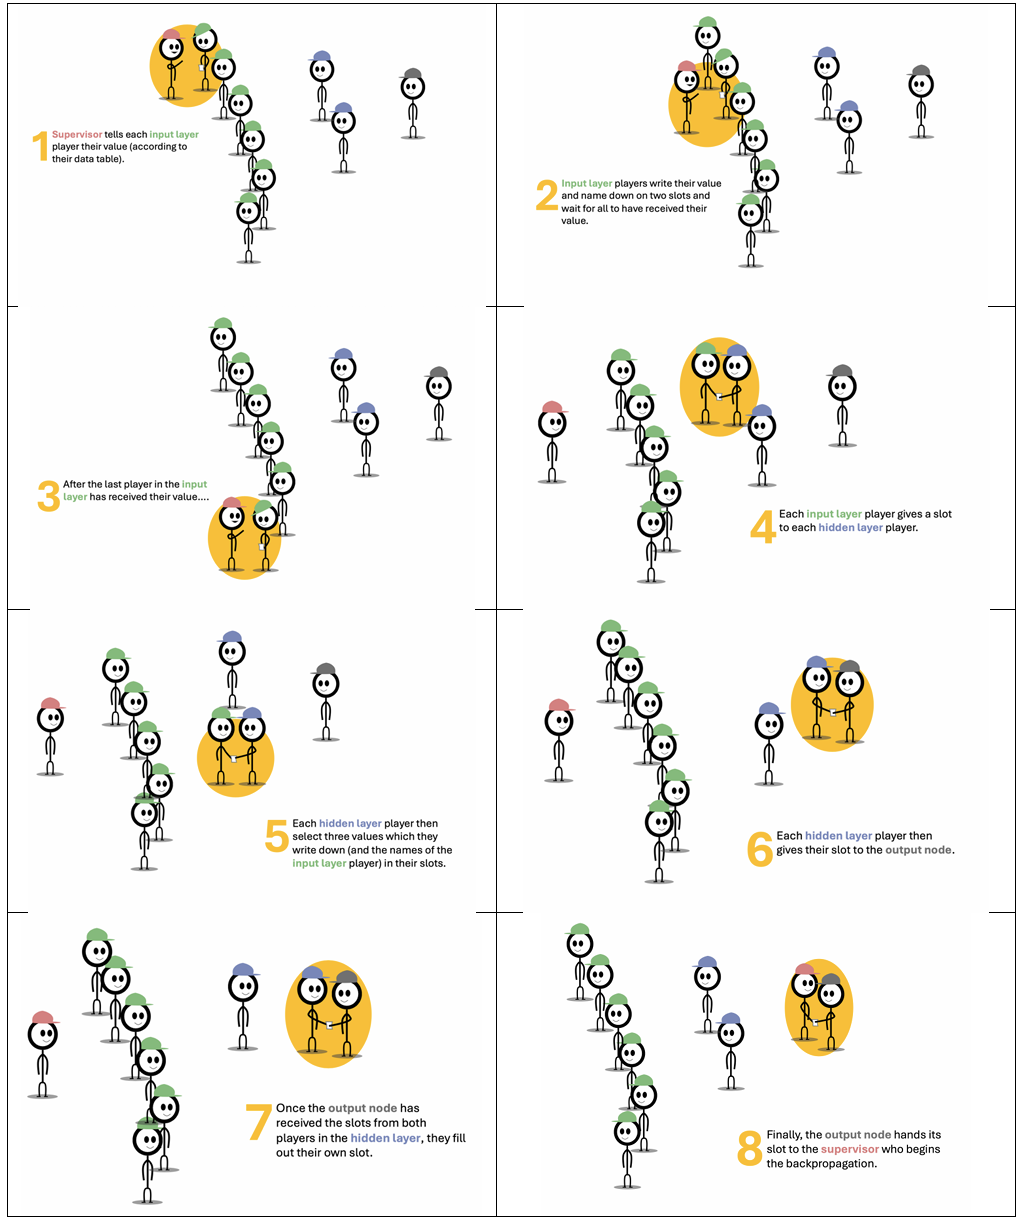
Here’s how Salomey’s classroom activity works. Sets of students act out the processes of training a neural network, including forward propagation, evaluation, and backpropagation. They take on the “roles’’ of some of the concepts of a neural network. One student acts as the supervisor, six students act as the input layer, two as the hidden layer, and one as the output layer.

Keeping it simple: Concepts and data

Key concepts are simplified for students:

  • Forward propagation: The hidden layer players randomly select a set of farms (three of the six sets of input values), which reflects how weights are often set to random values at the start.
  • Evaluation: The student acting as the output layer compares the prediction (whether crop disease is present or not) to the actual value for the farm to assess the error, similar to a loss function.
  • Backpropagation: Inspired by MIT’s RAISE curriculum, this stage is modelled on establishing trust. Players in the hidden and output layers modify their trust in the previous layers (by adding or removing ropes) based on the accuracy of the prediction (if the farm has disease).

Simple numerical data about the features of the problem are given to the students, such as whether the “Temperature” is suitable (0=No, 1=Yes), if there are “Spots” on the plant (0=No, 1=Yes), if “Fertilizer’’ has been used, whether the “Leaf colour’’ is green or not (see Table 1). Importantly, each of the six features given are represented by the six “input layer” students. So each student can ‘process’ each feature as the data for a given farm is used to train the model. Cards are used to represent the data values passed between layers. And this is where the ropes come into play, as they are used to represent the connections between the nodes in the layers.

Table 1: This data table was given to the student assigned the “Supervisor” role in each group and contains both relevant and irrelevant data to “train” their neural network.

Instructions for each role

Written role-specific instructions are provided for the students to follow, for example, the Supervisor is given three steps to follow for the forward propagation stage, and the Input Layer students receive a different set of instructions and so on. The detail of the role play is shown in the instruction sheets (see Figure 1).

Figure 1: Detailed explanation of the eight steps of the role-play activity that Salomey developed. Click to enlarge.

Why the ropes are important

Using ropes to connect the nodes becomes most important at the reverse propagation stage. The clever part of this is that we can show an increase or decrease in the strength of connection by adding or removing ropes. For me, this is the ‘jam sandwich’ effect. This, I think, is probably the most significant learning point. Here, the number of ropes that connect the nodes in the layers are changed based on the strength of evidence that a particular feature is indicated, by the data, to be relevant to the output. In this case, whether “Temperature”, for example, has an implied effect on cocoa disease or not — based on the data, not on any preconceived rule. Simply put, if a farm did have disease then a rope is added, if a farm did not then a rope is removed. Or at a more abstracted level, if a particular neuron contributes towards the correct prediction, a rope is added, otherwise a rope is removed. In a real neural network, backpropagation involves complex maths, such as calculus that would not be accessible to students of this age. Therefore, the rope is an analogy that replaces something that would be impossible for these students to grasp if it was taught using the real-world implementation. 


Problem to be solved in the unplugged activity: Identify features that are relevant for detecting diseases

At the end of the activity, features (temperature, leaf color, family farm, etc.) with many rope connections are considered to be relevant for crop disease detection on the farm, whereas features with fewer rope connections are considered to be irrelevant for crop disease detection. The more ropes attached to a particular feature, e.g., temperature, represent its higher relevance in identifying crop disease on the farm. 


Activity design, follow-on and evaluation

As part of the design of this activity, Salomey has simplified technical language so that throughout the role play students use everyday terms and she has chosen a context that is relatable for the students. For example, she uses the language of trust, and the new thickness of a rope connection, rather than using technical terms such as weight, loss function, and the error of the network.

Salomey also designed a follow-on activity that uses pen and paper. In this version of the activity, which she calls a board game, the students draw lines to connect the nodes in the layers. The thickness of the lines connecting the nodes represent the strength of the trust (see Figure 2). 

Figure 2: An example of how students use the board game that Salomey designed to teach about neural networks, where the thickness of the lines between nodes represents the strength of trust.

Salomey also shared her evaluation of the resources. She conducted pre‑ and post‑intervention surveys with 39 teachers as part of the professional development on the AI teaching materials, and ten of those teachers implemented the unplugged activities in their classrooms. She reported that the teachers found the role-play activity was effective to demonstrate neural networks, that children worked independently to learn, and that some students who did not take part usually in class were engaged.

As well as sharing about her unplugged neural network activity, Salomey also talked about a set of AI stories that she has developed to teach about other aspects of AI applications. For example, the importance of fact-checking is demonstrated through a story about a young girl who fact-checked information she received from her friends about life in a city. 
If you would like to find out more about Salomey’s work, you can find related materials on our seminar website.

Join our next seminar

Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London) speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.

The post Do you have some rope? Then let’s teach about AI concepts appeared first on Raspberry Pi Foundation.
The challenges of measuring AI literacy

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/the-challenges-of-measuring-ai-literacy/

Measuring student understanding in computing education is not an easy task. As AI literacy becomes an important pillar in computing education, defining and accurately measuring students’ understanding of concepts and their skills is an even greater challenge.

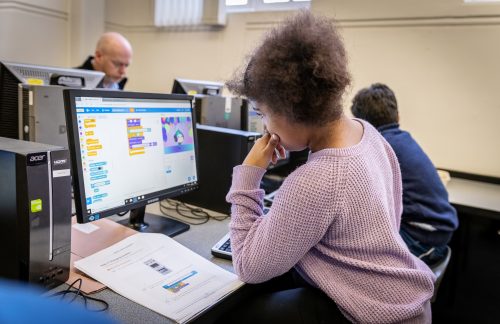
A girl doing Scratch coding in a Code Club classroom

In a recent seminar in our series on teaching about AI and data science, researcher Jesús Moreno-León (Universidad de Sevilla) talked about his work in developing assessment tools for computational thinking (CT) and AI literacy. Jesús is also co-founder of Programamos, a non-profit organisation that promotes the development of computational thinking, supporting teachers through training and sharing resources.

Jesús Moreno-León (Universidad de Sevilla/Programamos).
Jesús Moreno-León (Universidad de Sevilla/Programamos)

Developing assessment tools in computer science

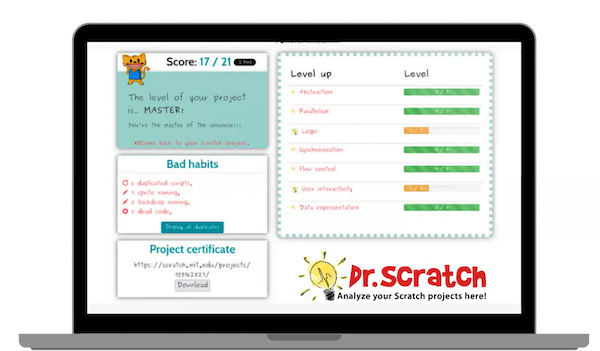
Jesús began by discussing the recent development of computer science assessment tools. Together with Gregorio Robles (Universidad Rey Juan Carlos), they created Dr Scratch, a web-based tool to assess the quality of Scratch projects and detect errors and bad programming habits (e.g. dead code). Projects are scored on the use of computational thinking concepts (e.g. parallelism, conditional logic) and the use of desirable programming practices (e.g. naming sprites, removing duplicate scripts) in order to give feedback to students and teachers to iteratively improve their Scratch projects.

Dr Scratch tool.
Dr Scratch tool.

Alongside measuring students’ programming skills, Jesús also shared work by Marcos Román-González (Universidad Nacional de Educación a Distancia) to develop the Computational Thinking test (CTt), a 28-item assessment tool designed to measure the computational thinking skills of students aged 10 to 16 years old. Two collaborators, María Zapata and Estafanía Martín (Universidad Rey Juan Carlos) further adapted these items to create the Beginners Computational Thinking test (or BCTt), an unplugged assessment suitable for younger learners aged 5 to 10 years old.

Teaching about AI in Spain

Jesús also described his more recent work at the Ministry of Education and Vocational Training in Spain to promote computer science at all educational levels. One initiative, La Escuela de Pensamiento Computacional e Inteligencia Artificial (or the School of Computational Thinking and Artificial Intelligence), supported Spanish teachers through training and resources to introduce CT and AI into the classroom. Over 400 teachers and 7000 teachers took part across Spain through unplugged activities and tools such as Machine Learning for Kids and LearningML, allowing students to classify text and images using machine learning. Older students created apps using the MIT App Inventor. When evaluating the design of the curriculum, they found they had strong instruments to measure the development of CT — such as the assessment tools described above — yet nothing to measure AI literacy.

The School of Computational Thinking and Artificial Intelligence curriculum.

A tool for measuring AI literacy

The lack of valid AI literacy assessment tools led the team to develop the AI Knowledge Test (or AIKT), a 14-item survey consisting of multiple-choice questions designed to measure students’ understanding of AI. The instrument was inspired by previous work in the field and relevant research (e.g. the AI4K12 framework).

An example from the AI Knowledge Test

An example of one of these items is presented below. Can you solve it? The answer is at the bottom of this article.

Q1. Which of the following strategies would be most appropriate for teaching a computer to recognise photos of apples?

  1. Train the computer with photos of dogs
  2. Train the computer with several photos of different apples, taken in different places and contexts
  3. Train the computer with several similar photos of the same apple, taken in the same place
  4. Train the computer with several identical copies of the same photo of an apple

Testing the test

In a study on the impact of programming activities on computational thinking and AI literacy in Spanish schools, the authors tested these knowledge-based items with over 2000 students to assess the reliability (e.g. internal consistency), or a measure of the quality of a survey or test. They found one item (“As a user, the legal regulation that is approved regarding AI systems will affect my life”) did not correlate with the other items. This left a total of 13 items which were found to have sufficient internal consistency — meaning how well each item correlated with one another to measure an underlying construct (i.e. “AI knowledge”). They concluded that the assessment tool needed a higher ceiling and needed to address common misconceptions. The authors also learned that teachers needed free and open-source tools with low barriers for entry, such as not needing registration, and were suitable for classroom use, such as limiting data sent to the cloud.

AI literacy in the generative era

With the rise of generative AI tools like ChatGPT or Google’s Gemini, Jesús and his colleagues felt their AI literacy assessment tool needed to focus on the capabilities of generative AI tools. They also felt they needed to take a broader view of AI and focus on additional dimensions, such as the social and ethical implications of AI tools. They are, therefore, currently revising their assessment items to align with several common frameworks, including the SEAME framework and AI Learning Priorities for All K–12 Students.

An example from the revised AI Knowledge Test

One of the revised items is presented below. Can you solve it? The answer is revealed below.

Q2. You have asked your students to design a decision tree to classify different fruits based on three characteristics: color, size, and shape. To check whether the following proposed solution is correct, you are going to test it with a small, round, yellow apple.

  1. Apple
  2. Watermelon
  3. Lemon
  4. Banana

Learn more about this work

Jesús concluded the seminar by describing his intentions to collaborate with others to test the revised AI literacy instrument with students in early 2026. We look forward to hearing about their results!

You can watch Jesús’s whole seminar here:

If you are interested to learn more about Jesús and his work, you can read about his development of the AI Knowledge Test (or AIKT) here and the Computational Thinking test (CTt) here or look at the original items here. You can also learn about the Beginners Computational Thinking test (BCTt) by watching a Raspberry Pi research seminar about it or reading about it here.

Join our next seminar

In our current seminar series, we’re exploring applied AI and how AI can be taught across the curriculum. In our next seminar in this series on 17 March at 17.00 UK time, we welcome Rebecca Fiebrink (University of the Arts London) who will explore the questions of how and why we might teach AI for creative practitioners, including children, students, and professionals.

To take part in the seminar, click the button below to register. We hope to see you there.

The schedule of our upcoming seminars is available online. You can catch up on past seminars on our blog and on the previous seminars and recordings page.


Answers

  • Q1: 2
  • Q2: 3

The post The challenges of measuring AI literacy appeared first on Raspberry Pi Foundation.
Embodied machine learning: From research ideas to classroom activities

Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/embodied-machine-learning-from-research-ideas-to-classroom-activities/

Where do great research ideas come from in computer science education? We might think of research breakthroughs as a single moment of genius, but in reality impactful research is often the result of many years of iterative development. In November’s research seminar, we heard from Karl-Emil Kjær Bilstrup, a researcher at the University of Copenhagen, about his work to develop ML-Machine. This work uses embodied learning principles and the BBC micro:bit to introduce learners to machine learning concepts. Findings from this research have been used to develop the micro:bit CreateAI resources, and in this blog, we will explain the research journey from initial small-scale work to educational resources used by many young learners around the world.

Karl-Emil Kjær Bilstrup, a tool designer and researcher from the University of Copenhagen

From hypothetical ethics to concrete machines

In Karl-Emil’s first research study, students used prompt cards to develop ideas for machine learning applications that could solve real-world problems, and to discuss the ethical dilemmas associated with their solutions. Students found it difficult to address these ethical dilemmas in their designs; for example, their ideas often featured a trade-off of user privacy. The findings from this research informed Karl-Emil’s next study, which moved from hypothetical scenarios to implementing machine learning in real-world settings. 

The ‘Machine Learning Machine’ study made machine learning processes tangible for students through the use of two physical boxes, shown in the picture below. Students created drawings and fed them into the first box to train a model, and then tested the model by placing new drawings under a camera in the second box and having the model produce predictions of what the drawings showed. For example, students could draw pictures of the sun to represent daytime and the moon to represent nighttime to train a model to predict whether new drawings represented day or night. The machine was built for slow interaction, giving students time to think about the concepts and practices that they were developing. In a follow-up study, a new version of the Machine Learning Machine had been designed, which was controlled using a graphical user interface (GUI). This allowed users to “unbox” and influence parts of the machine learning process. For example, students could adjust the number of complete passes (called ‘epochs’) through the training data to improve the model’s accuracy. 

The two components of the Machine Learning Machine: the training box (left) and the evaluator box (right)

The two studies with the Machine Learning Machines provided many useful findings for teaching about machine learning with K–12 (primary and secondary) learners. However, two constraints remained: firstly, there were limited opportunities for whole-class work because there was only one Machine Learning Machine, and secondly, learning experiences needed to be better connected to examples from students’ daily lives. As a result, the next iteration in Karl-Emil’s research involved using the micro:bit, which ensured access to a tangible device for every student, and a new graphical platform called ML-Machine that students could interact with.

Machine learning and the micro:bit

The micro:bit is a small, programmable computing device that features sensors to gather data from the immediate environment. For example, the accelerometer is a motion sensor that can detect when the micro:bit is tilted from left to right, backwards and forwards, and up and down. Using the micro:bit with ML-Machine and some common household objects, students can create simple machine learning models that use data from the micro:bit’s accelerometer to detect whether the micro:bit is moving. This is a very different approach from rule-based programs on the micro:bit, where students might use programming constructs such as if statements to detect movement if the numerical reading from the accelerometer is above a certain value. Here, a machine learning model trained using a set of 20 examples is used to analyse live data readings and produce predictions about whether the micro:bit is moving.

A visualisation of a simple machine learning model to detect whether a micro:bit is being shaken or is still

In our seminar, Karl-Emil gave a live demonstration of the ML-Machine toolkit, so we highly recommend watching the recording to see how this toolkit brings machine learning concepts to life. 

ML-Machine is the precursor to the micro:bit CreateAI resources, and the software is fully open-source. However, the innovation doesn’t stop there: Karl-Emil also explained that he is currently developing a new tool called math.ml-machine.org, where students can train a neural network and see a visualised k-nearest neighbour model to explore how a model makes predictions. The research journey is continuing, with new possibilities for educational opportunities to teach about machine learning.

Embodied learning

The idea of embodied learning is interwoven throughout all of Karl-Emil’s research projects and is a cornerstone of all of his work. Embodied learning suggests that we learn more effectively when our whole body is involved in the learning process, not just our minds. For example, in the work described in this seminar, the Machine Learning Machines and the micro:bit were all tangible devices that students could touch and see. 

Embodied learning is particularly important in activities that involve working with data-driven systems. In traditional programming activities, the flow of code can be traced transparently through a program. However, machine learning models are more opaque, and their outputs cannot be traced step by step. Students can benefit from using bodily movements and sensorimotor information to help understand machine learning concepts. 

The ML-Machine toolkit was designed to support students to learn through embodied learning in three different ways:

  1. Enacting machine learning processes: Students used bodily movement to collect the data samples needed for the ML-Machine model to detect and predict gestures 
  2. Using machine learning as a design material: Students created concrete ‘objects-to-think-with’, which helps form deeper connections to abstract concepts
  3. Embodied exploration of machine learning: Students experienced how their bodily movements were translated into data points on the screen
Secondary school age learners in a computing classroom.

Embodied learning helped students grasp concepts such as data quality. They could see how their bodily movements were being translated into digital data, and could spot when movements that appeared different to them were being classified as similar by the ML-Machine model. One case study participant described that the immediate feedback on screen made the concept of machine learning feel as if it were “coming to life as they [the students] manipulate something themselves and they’ve got control over it”.

Find out more

Karl-Emil’s work shows how research ideas can be used in the classroom through a cycle of discovery, design, and reflection. From prompt cards exploring ethics to tangible machines and the micro:bit-based ML-Machine, his research shows how embodied learning can make complex ideas like machine learning not only understandable, but deeply engaging for young learners. The micro:bit CreateAI resources are a great example of how research findings can evolve into accessible, hands-on tools that empower educators and students alike. As this work continues to grow, it invites us to imagine new ways for learners to experience machine learning not as abstract theory, but as something they can see, feel, and shape with their own hands.

If you’d like to try out some of the ideas from this seminar, here are some useful resources: 

  • Explore machine learning projects using the micro:bit: micro:bit CreateAI and our Dance detector project are great places to start
  • Find out more about the research: Read more about Karl-Emil’s work in this open-access paper
  • Investigate new tools: Explore neural networks and k-nearest neighbours algorithms in the new maths-focused version of ML-Machine at math.ml-machine.org

Join our next seminar

Join us at our next seminar on Tuesday 17 March from 17:00 to 18:30 GMT to hear Rebecca Fiebrink (University of the Arts London speak about teaching AI for creative practitioners. This will be the second seminar in our new series on how to teach about AI across disciplines. We hope to see you there!

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.

The post Embodied machine learning: From research ideas to classroom activities appeared first on Raspberry Pi Foundation.
How to put data first in K–12 AI education by using data case studies

Post Syndicated from Manni Cheung original https://www.raspberrypi.org/blog/how-to-put-data-first-in-k-12-ai-education-by-using-data-case-studies/

In Germany, as in many countries, AI topics are rapidly entering formal computer science education. Yet, this haste often risks us focusing on fleeting technological developments rather than fundamental concepts. As computer science educator Viktoriya Olari, from Free University of Berlin, discovered in her research, the fundamental role of data, which powers most modern AI systems, is critically underestimated in many existing frameworks. If students are to become responsible designers of such systems, they can’t afford to treat AI as an opaque box. Rather, they must first master the messy, human process that begins with the data itself.

Viktoriya Olari, from Free University of Berlin.
Viktoriya Olari

In our October research seminar, Viktoriya shared the results of her work over the last four years on how schools can shift the focus from the latest technologies to the underlying data. Her research offers a clear structure for what young people should learn about data and how teachers can make it work inside ordinary classrooms.

Why begin with data?

Viktoriya’s analysis of existing AI education frameworks found the data domain is underrepresented, with essentials such as data cleaning often not addressed at all. She argues that, because modern AI systems are data driven, students need both language and routines for working with data: being able to name concepts like training vs test data, data quality, and bias, and to explain practices such as collection, cleaning, and pre-processing. That’s the rationale for teaching data concepts and practices first, and then placing modelling inside an explicit, staged lifecycle.

Word clouds for two foundational components: data concepts and data practices.
A slide from Viktoriya’s presentation. Click to enlarge.

Her talk presented this argument in the German school context, where AI topics are entering state curricula quickly. Her critique targets how existing frameworks fail to address data and how that gap undermines responsible evaluation and design. The proposed model centres data by pairing an eight-stage, data-driven lifecycle with a curated set of key concepts and practices, and by making “data-based judgment skills” a key outcome.

Viktoriya’s work organises this understanding into two foundational components: data concepts (the vocabulary, e.g. training/test data, data quality, overfitting) and data practices (the actions, e.g. collect, clean, train, evaluate).

A lifecycle for learning

Viktoriya’s framework is built around an eight-stage data lifecycle, stretching from defining a task through gathering, preparing, modeling, evaluating, and finally sharing or archiving results. Inside that backbone she has identified two layers of learning targets:

  • Data concepts – roughly a hundred ideas that give teachers and students a common language, from “training vs. test data” and “bias” to “features”, “labels”, and “provenance”.
  • Data practices – 28 kinds of hands-on work (and 69 subpractices) that materialise those ideas: for instance collecting, cleaning, splitting datasets, checking quality, training and evaluating models, and handling privacy and deletion responsibly.

More details are available in her work on data-related concepts and practice.

Viktoriya’s 8-stage process model of the data-driven lifecycle.
A slide from Viktoriya’s presentation. Click to enlarge.

Viktoriya’s 8-stage process model of the data-driven lifecycle. It serves as a guide for curriculum developers and teachers, outlining 28 key data-related practices and providing 69 examples of subpractices for use in K–12 computer science education.

A collection of 133 key data-related concepts.
A slide from Viktoriya’s presentation. Click to enlarge.

A collection of 133 key data-related concepts. These concepts are organised according to the eight stages of the data-driven lifecycle and provide the foundational vocabulary for teaching AI education.

Making it teachable

Viktoriya’s team set out to redesign the format so that real data work could happen within ordinary lessons. They ended up with three “Data Case Study” architectures, each using authentic datasets and domain questions. The materials are supported by Orange 3, an unplugged machine learning and data visualisations tool familiar to the teachers participating. Variants emerged across three design cycles to address specific challenges, but teachers choose among them based on learning objectives and class context.

  1. Bottom-up: Students create a workflow step by step (e.g. import, inspect, clean, transform, split, train, evaluate). This approach is excellent for procedural fluency, but teachers reported an over-emphasis on operating Orange and too little reflection on the lifecycle unless explicit reflection is added. 
  2. Top-down: Students start from a prepared workflow, read plots, infer the role of each branch, identify issues in the data/practices, and justify changes. This architecture directly counters the reflection gap seen in bottom-up and leans into reasoning rather than routine. 
  3. Puzzle-like: Using “widgets,” visualisations of data tables, that stand for parts of a data pipeline, students rebuild a valid flow collaboratively. This encourages discussion, works without devices, and makes thinking visible.
The school-specific data case study
A slide from Viktoriya’s presentation.

The data case study method uses real-world data and context to help students achieve three key learning outcomes: go through the data-driven lifecycle, reflect on data practices and concepts in a criteria-guided manner, and develop data-based problem-solving and judgment skills.

What happened in the German classrooms

Viktoriya’s team ran three design cycles with small groups in Germany, with students aged 14 to 15. Each cycle lasted around 48 hours of teaching. Because participating teachers already knew Orange 3, the emphasis was on pedagogy rather than software training.

The projects drew on manageable real-world data: spreadsheets, time-series sets, a few geographical samples. Two examples are:

  • Forecasting Berlin air quality – Students explored how data quality, feature choice, and evaluation metrics shape predictions, then argued which model best answered the civic question.
  • Classifying Tasmanian abalone – A deceptively simple dataset that invites talk about imbalance, feature engineering, and what counts as “good enough” accuracy.

Some groups experimented with collecting their own sensor data, a plan that occasionally failed when the hardware didn’t cooperate. However, even that became part of the lesson: reliability, risk, and missing data are real features of data science, not mistakes to hide.

A computing classroom filled with learners

Student work reflected the three architectures. In the bottom-up groups, guided builds produced complete workflows and concise reflections, while top-down groups submitted annotated screenshots and critiques, and the puzzle-based lessons ended with posters and verbal presentations. Across them all, assessment focused on reasoning: not whether the “right” model appeared, but whether students could explain the stage they were in and justify their choices.

Teaching resources

Everything Viktoriya described is open and classroom-ready (currently in German). The computingeducation.de/proj-datacases hub hosts teacher guides, student tasks, and sample Orange 3 files. The growing library of data cases covers topics from climate data to air quality analytics.

Why it matters now

In the UK, a curriculum review has been recently released and along with the Government’s response. Across Europe and beyond, education systems are racing to add AI content to their curricula. Tools will come and go, and benchmarks will keep moving. What endures is the capacity to reason about data: to know what stage of work you’re in, what evidence supports your decisions, and what trade-offs you’re making. That is why Viktoriya’s contribution is unique — it gives teachers a map, a shared vocabulary, and practical ways to make data visible and the focus of discussion in schools.

You can read this blog to see how we’ve used Viktoriya’s framework in our work designing a data science curriculum for schools.

Join our next seminar

Join us at our seminar on Tuesday 27 January from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about how to teach about neural networks in Junior High Schools in Ghana.

To sign up and take part, click the button below. We’ll then send you information about joining.

We hope to see you there. This will be the final seminar in our series on teaching about AI and data science — the next series focuses on how to teach about applied AI across subjects and disciplines.

You can view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.


Teachers in England, take part in our new data science study

We’re looking for upper key stage 2 teachers in England who want to join our new collaborative study exploring how to teach learners aged 9 to 11 about data-driven computing. The study will look at:

  • How Computing teachers currently approach topics related to data-driven computing
  • What key ideas pupils need to understand
  • How pupils make sense of data and probability

Our aim for the study is to find practical ways for Computing teachers to build young people’s confidence in working with data in lessons. The study will involve two workshops held throughout 2026.

Register your interest by filling in this form.

The post How to put data first in K–12 AI education by using data case studies appeared first on Raspberry Pi Foundation.
How can we teach about AI in the arts, humanities and sciences? Research seminar series 2026

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/how-can-we-teach-about-ai-in-the-arts-humanities-and-sciences-research-seminar-series-2026/

For the last five years, once a month, we have hosted an online seminar sharing computing education research. Seminars are organised as usually year-long series with changing themes. In 2025, for example, our theme was ‘Teaching about AI and data science’. In 2024, it was ‘Teaching programming (with or without AI)’.

Three people look at sticky notes on a whiteboard.

It is not surprising that for the last few years our focus has been on AI technology, and for 2026 we will continue this. But we will shift from showcasing how computing education research is changing teaching and learning in computing lessons, to showcasing how computing education research in other disciplines, such as art or geography, is starting to include teaching about AI. For example, art lessons may change so that learners find out how professional artists are using AI tools to create arts. Or geography lessons may change so that learners discover how professional geographers are using AI to make predictions about physical or human aspects of geography, such as volcanic activity and global warming.

Our series for 2026 is called ‘Applied AI’. This title recognises that AI technology is applied across contexts, across careers, across disciplines, and this means what we teach across school subjects will change.

Encouraging a pull from disciplines, rather than a push from computer science

The majority of resources and professional development material related to teaching about AI have been developed by the computer science community. For example, we have developed the popular Experience AI resources in collaboration with Google DeepMind. In these resources, the contexts were carefully selected to represent real-world examples across disciplines, and to to enable the teaching of particular technical or social and ethical concepts. This could be described as “a push” of content from computing towards other disciplines. For example, to enable teaching about the ethical issues around plagiarism, an art context is used in the Experience AI resources; to enable teaching about the potential benefits of using AI tools, an ecological geography context is used.

Example activity from the Experience AI resources, focused on ecology

AI applications are always situated within a particular topic. Most current AI applications are data-driven: vast amounts of data are collected and processed to produce models that can then either be used to generate outputs or make predictions. For example, data about artworks can be collected and used to train a model for generating outputs similar to the artworks; this is an application of AI in the art discipline. Or data on wild fires can be collected and used to train a model for making predictions about current or prospective fires; this is an application of AI in the geography discipline.

Example activity from the Experience AI resources, focused on meteorology

In reality, the best people to recognise how AI technology is being applied in a discipline and what students in that discipline should be taught about these applications are the people working in the discipline, for example the art and geography teachers. Computer science educators can work to build the technical understanding and the general social and ethical understanding that is common across applications. But the detail of how AI technology is changing a discipline can only truly be understood by the respective community, by the artists and art educators, by the geographers and the geography educators.

An emerging focus

At present, though, most educators are grappling with how they can use AI tools for productivity, such as creating lesson plans, or answering emails. Or they are looking at how they can use AI for general teaching and learning, for example for personalisation, say for students with additional needs. The idea that their underpinning discipline is changing is, perhaps, not yet on teachers’ radar. But at universities, such as in undergraduate courses, and in the world of work, education and training are changing. Data science courses are now being offered across faculties, including science, geography, language, and art faculties. These changes will start to filter down to school-based education via curriculum change. While some resources and professional development materials addressing this shift are already becoming available, change is still fragile and patchy.

Raising awareness, building community and a common language

The aims of our Applied AI research seminar series in 2026 are to start to:

  • Raise awareness of the forthcoming changes that applying AI will bring to disciplines
  • Build a cross-discipline community
  • Think about a common language that could be used across disciplines

If we can start to agree on what common concepts could be taught in the arts, sciences and humanities, it gives us a better chance to:

  • Understand how to use AI as it is applied in different disciplines
  • Help students to build useful mental models and develop the agency and critical thinking skills they need to evaluate these applications and decide when and how to use them and how far to trust them

We need your help

To make our 2026 series a success, we need to spread the word about our seminars to groups of educators, researchers, industry and policy makers across the arts, sciences, and humanities.

Please tell those you know in these groups about the seminar series, and share it through your social media and other networks. If you have ideas for subject associations we could connect with or publications where we can write about our series, please let us know.

Join our ‘Applied AI’ seminar series

We have already arranged the following seminars across 2026 and will add more speakers for the remaining monthly slots soon. Seminars always take place online on Tuesdays at 17:00 to 18:30 UK time.

  • 10 February: Social studies, public policy, economics and AI — Thema Monroe-White (George Mason University, USA)
  • 17 March: Arts and AI — Rebecca Fiebrink (University of the Arts London, UK)
  • 14 April: Healthcare and AI — Kathryn Jessen Eller (Data Science, AI & You (DSAIY) in Healthcare, USA)
  • 14 July: Literacy and AI — Dan Verständig (Goethe University Frankfurt, Germany)
  • 8 September: History and AI — Jie Chao (The Concord Consortium)
  • 6 October: Robotics and AI — Eleni Petraki & Damith Herath (University of Canberra, Australia)
  • 10 November: Geography and AI — Doreen Boyd (University of Nottingham, UK)

To sign up and take part, click the button below. We’ll then send you information about joining. We hope to see you there.

You can view the schedule and details of our upcoming seminars on this page, and catch up on past seminars on our previous seminars page.


PS If you are teaching upper primary school learners in England, you can currently register your interest in our upcoming collaborative study on data science education. You’ll find out more about some of the research we’ve done in this area in this blog post.

The post How can we teach about AI in the arts, humanities and sciences? Research seminar series 2026 appeared first on Raspberry Pi Foundation.
2025 highlights from the Raspberry Pi Computing Education Research Centre

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/2025-highlights-from-the-raspberry-pi-computing-education-research-centre/

It’s been over a year since I last wrote an update on this blog about our research and as we’ve just published our 2025 Annual Report, this is an ideal opportunity to share what we’ve been working on at the Raspberry Pi Computing Education Research Centre.

At our AI education workshop in early 2025.

We are a research centre based in the Department of Computer Science and Technology at the University of Cambridge, with a team that spans the university and the Raspberry Pi Foundation. We conduct research into many aspects of the teaching and learning of computing and AI and we work closely with schools, teachers and young people to ensure our research is applicable to practice.

Below I highlight some of the projects we’ve worked on in the academic year 2024-2025:

  • Computing Around the World
  • AI education
  • Programming education
  • Physical computing (EPICS project)
  • Teacher action research (TICE project)

Computing Around the World

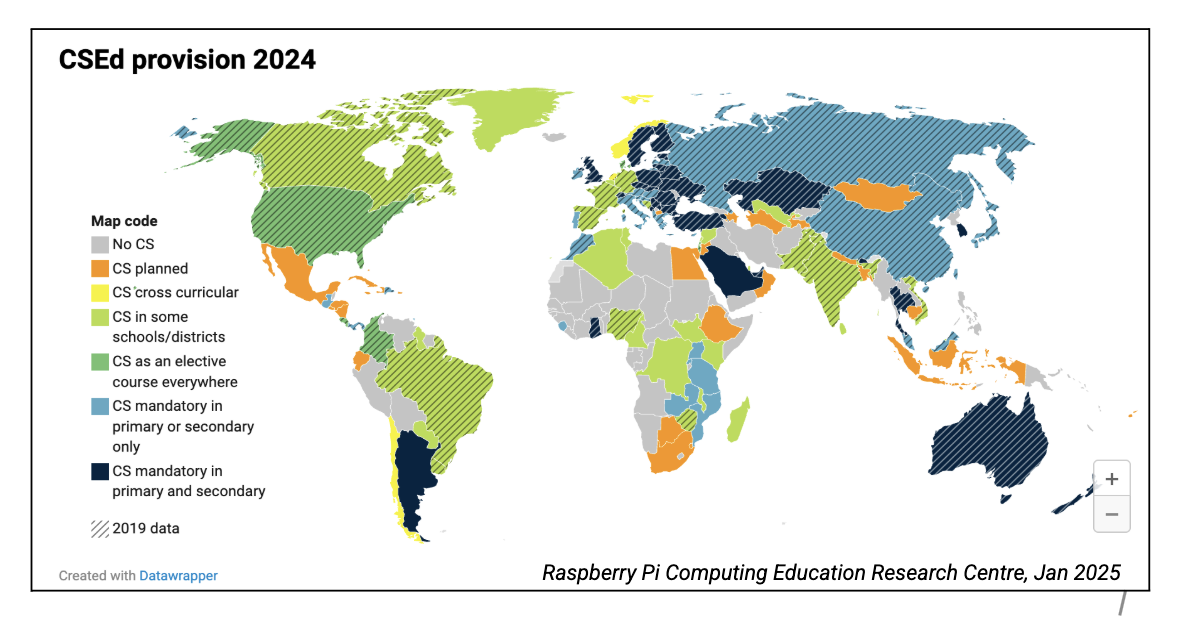
As I’ve written on this blog before, computing education is a global challenge. In one of the Research Centre’s projects, we are looking at how computing education is spreading around the world.

Computing education in countries around the world
Computing education in countries around the world.

We found that between 2019 and 2024 the number of countries offering computing education had doubled, and that two thirds of all countries now offer, or have concrete plans to offer, computing education. This research has already been highlighted in the Stanford AI Index, and we are considering repeating the analysis in future years in order to have the most accurate and up-to-date information displayed in our map.

AI education

We have a number of projects in the area of AI education.

Teaching about AI

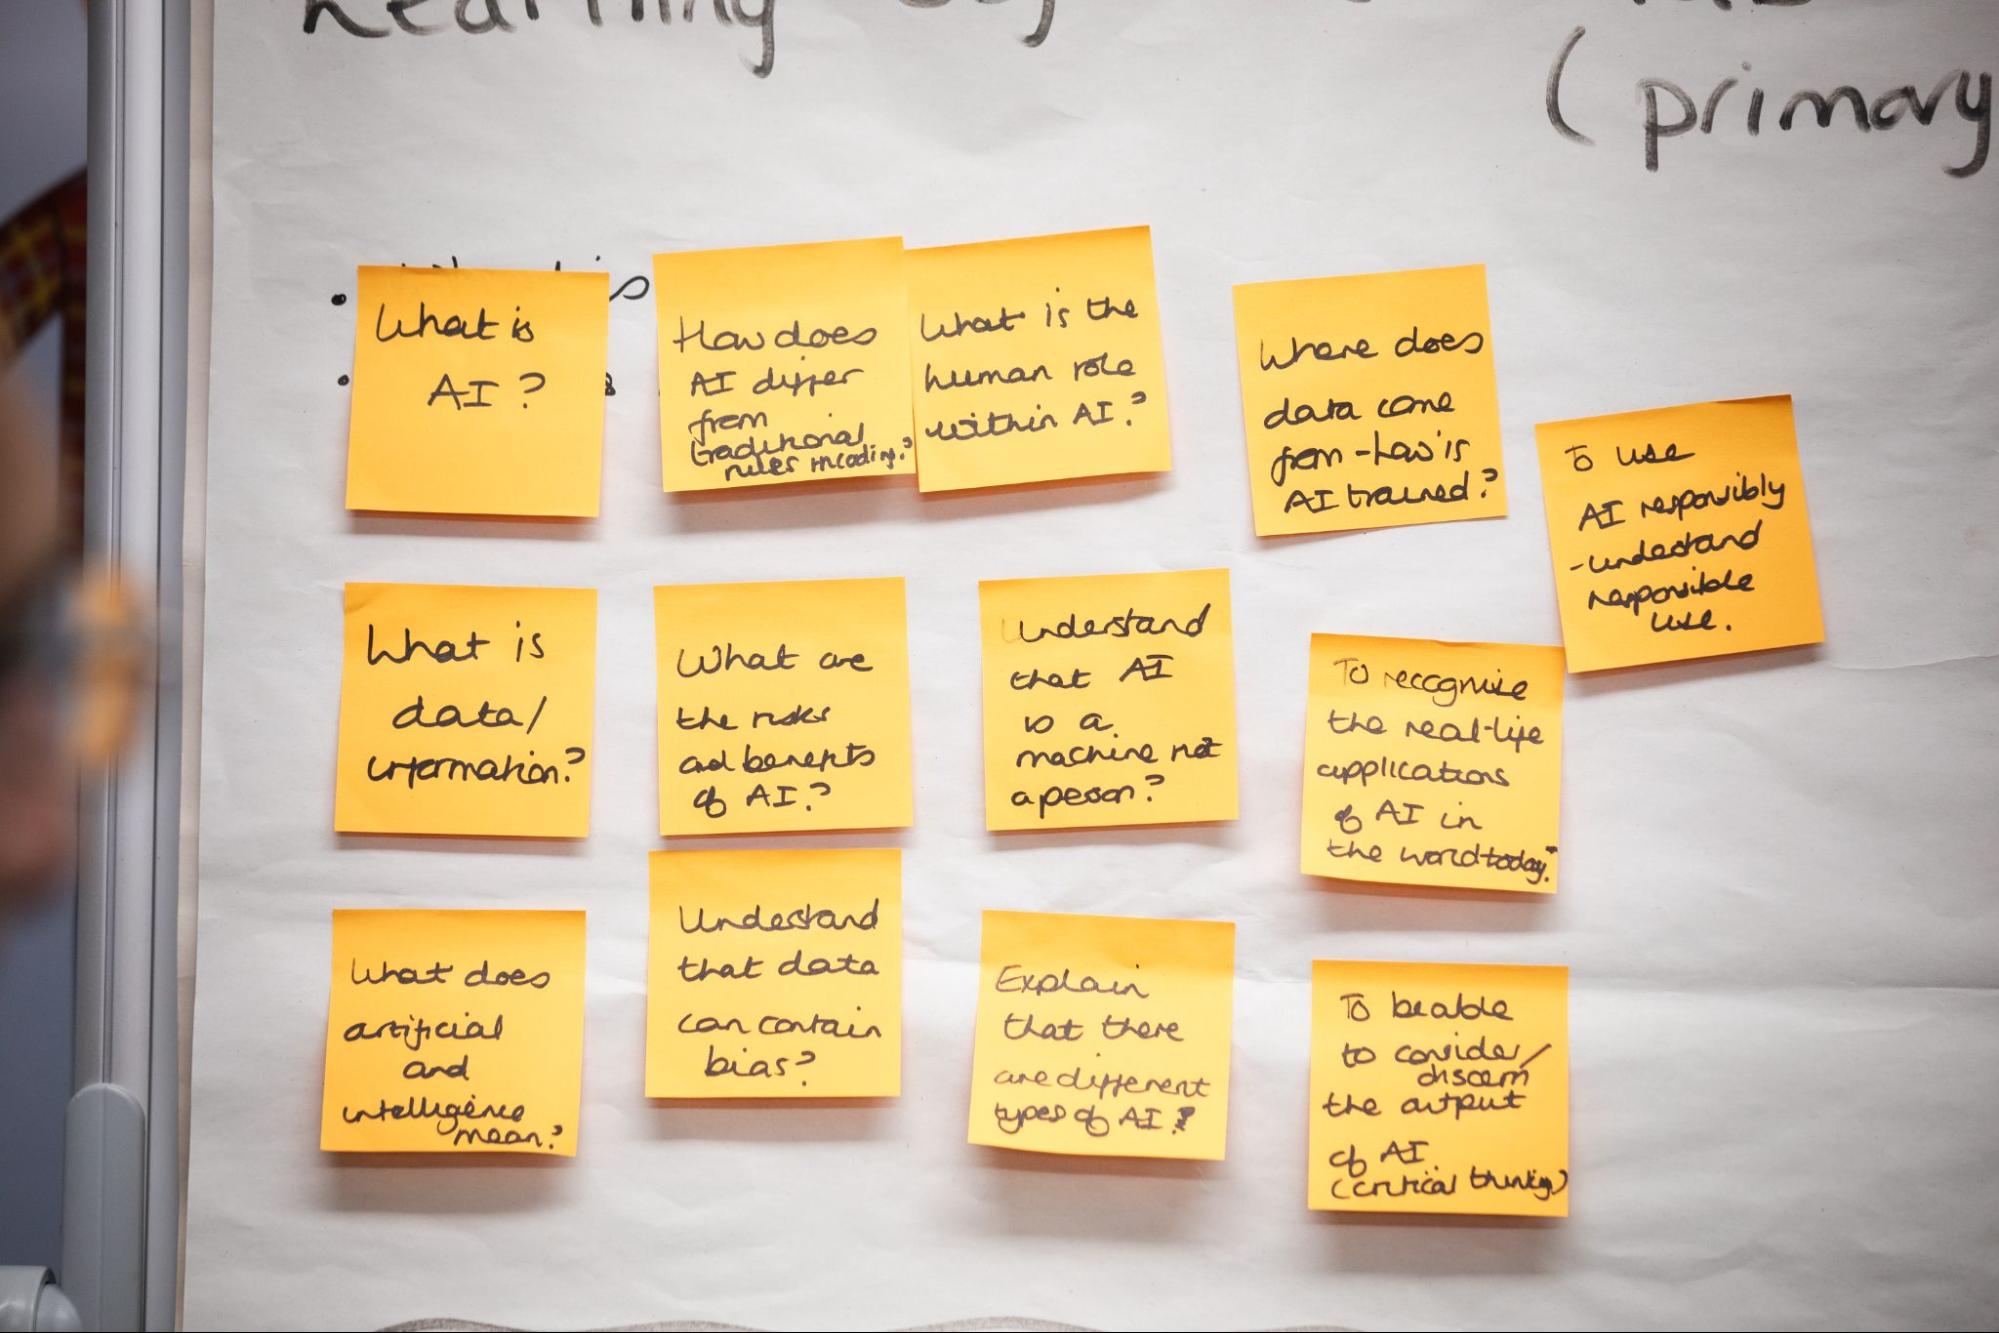
We are very interested in how to teach about AI, and held a workshop with teachers who were interested in the teaching of AI in February. Following on from the workshop results, we are interviewing more stakeholders, including UK-based experts, teachers and students, about their perspectives on concepts and skills that should be taught as part of an AI curriculum.

Notes at our teacher workshop about AI
Notes at our workshop about AI education.

We’re also researching data science and data ethics education, which are foundational aspects of AI literacy. Most of the current AI systems are data-driven, having been trained on vast amounts of data. Therefore students need to understand about data and data science if they are to learn about AI systems. Therefore we’ve conducted two detailed literature reviews on data science and on data ethics this year. The first of these will be published in March at the WiPSCE conference.

Unplugged AI in Ghana

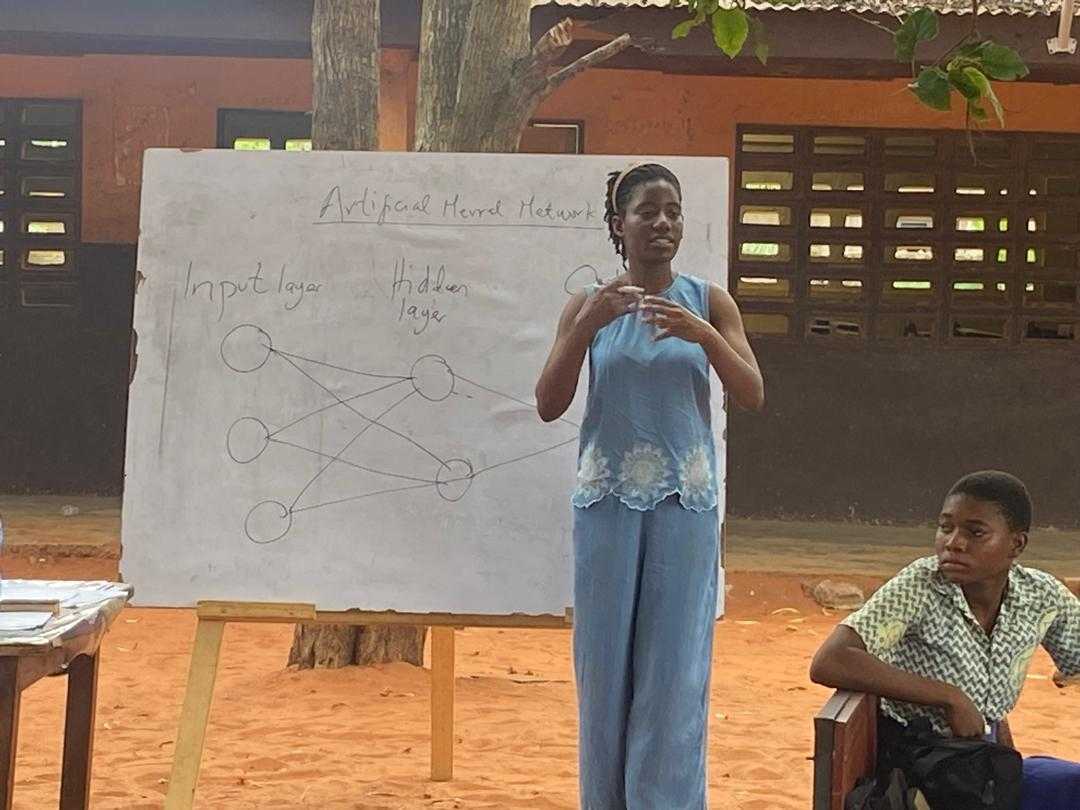
One of our PhD students, Salomey Addo, has been examining how AI is taught in Ghana, where it is part of the curriculum for young people between ages 12 and 15. This year Salomey published a paper reporting that Ghanaian teachers have positive attitudes towards teaching AI but feel unprepared for it. She’s also developed unplugged resources to teach about artificial neural networks (ANNs).

PhD student Salomey explaining how the unplugged resources worked in a teacher PD session in Ghana
PhD student Salomey explaining how the unplugged resources worked in a teacher PD session in Ghana.

ANNs are a fundamental technology used in a variety of AI systems, including image recognition and language translation systems. While ANNs are included in the Ghanaian AI curriculum, Salomey observed that teachers had difficulty with this particular topic The resources she developed are directly inspired by this, and involved teaching through role play and a board game.

Using AI in learning and teaching computing

This is an area we’ve also done some research in in the past year.

Carrie Anne Philbin published a paper in September showing that — at least in higher education — much of the use of generative AI in computing education is just duplicating the way teachers might already teach, and is primarily passive from a students’ perspective.

Meanwhile Katharine Childs and Veronica Cucuiat have been looking at how large language models (LLMs) can support secondary school programming education by helping students understand programming error messages. 

Programming education: Learning to debug

Text-based programming is a topic featured in many computing curricula around the world. Teachers and researchers know that younger learners, for example at the lower secondary school level, can find debugging text-based programs very challenging. Although we’ve seen decades of research around programming and debugging focusing on learners who are in higher education, very little research has been done with school-age students.

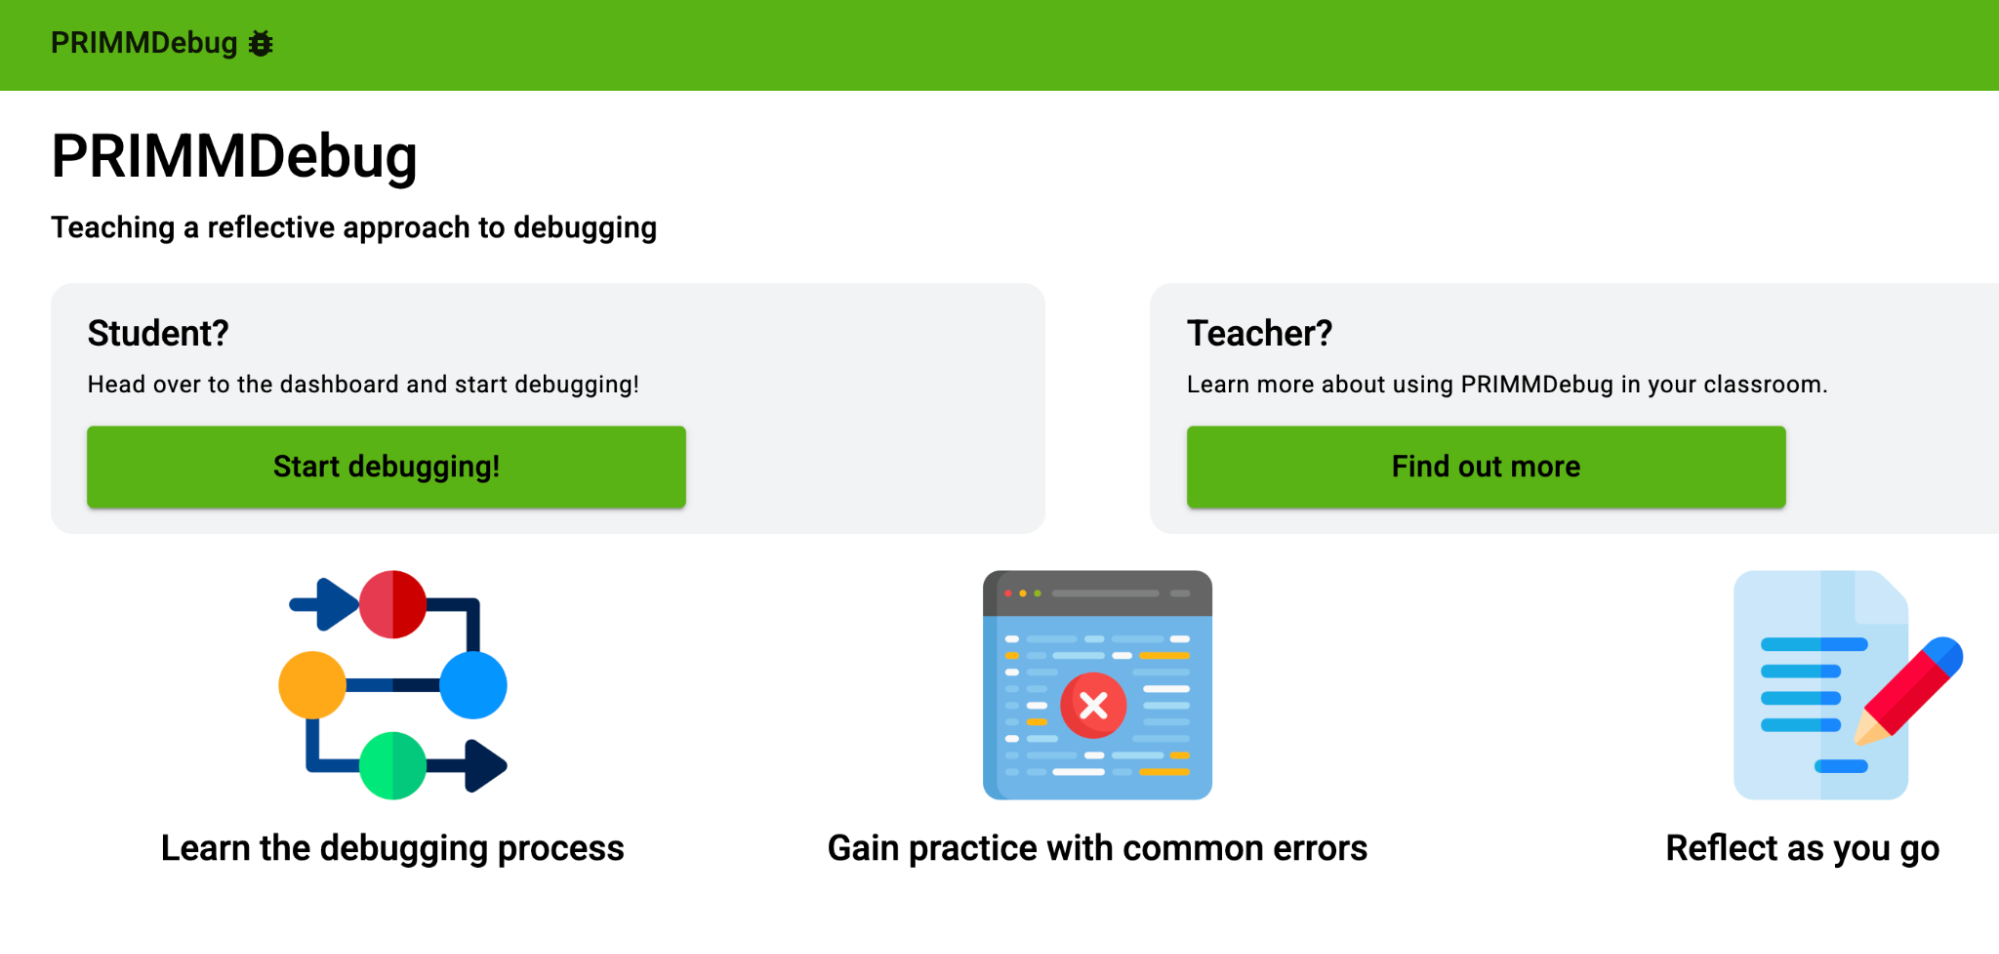
The interface of the PRIMMDebug tool
The interface of the PRIMMDebug tool.

In his research, Laurie Gale, a final-year PhD student at the Research Centre, found that learners were impatient to fix programs by trial and error, without figuring out what the real problemwas with their code or the underlying algorithm. He subsequently developed a tool called PRIMM Debug, which supports a more reflective and systematic approach to debugging. This tool enables learners to slow down when they are programming and to be more reflective. You can read more about it on the Research Centre website, and also catch up on the Foundation research seminar where he presented his work.

EPICS: Physical computing in school

As part of a 5-year longitudinal project, running across the whole UK and the first project of its kind, we are looking at how physical computing impacts primary and secondary school learners. We’re investigating the effect of physical computing on learners’ creativity, agency and confidence, over time and at particular points known to be important for their subject choices. We are working with a wonderful set of partner primary schools who we visit each year.

Young learners coding a microbit project.
Young people using a micro:bit.

This year we reported some of our first results, which point to teachers’ perceptions of physical computing being engaging and inclusive for primary-aged children. Starting next spring, we will be carrying out our third year of data collection with our pupil cohort, who have reached the age of 10 to 11.

We’ll also be running a survey next summer for upper primary-aged children and their teachers. Please sign up for our Teacher Research Network newsletter to be the first to hear about taking part in this survey.

Teacher Inquiry in Computing Education (TICE)

As part of our TICE project we support teachers to conduct their own action research projects. This is a collaborative project, involving academics across the UK who volunteer to support teachers. The goal is to enable teachers to take a deep dive into a curriculum topic, a pedagogical approach, or a new resource, or to address a wider issue such as gender diversity or accessibility, to inform a change in their practice.

This year 16 teachers published their reports in our Teacher Research Booklet, and many also presented their findings online at CAS events or at the KCL-CAS London conference and the CAS National Conference. We’re very proud of them!

TICE participant Will Grey presenting at the KCL-CAS Conference in July 2025
TICE participant Will Grey presenting at the KCL-CAS Conference in July 2025.

Two of our TICE teachers will be also presenting their research at an academic conference to be held in January. Congratulations to Will Grey and Joanne Hodge!

Get involved

There are many other projects you can find out about on our website and in our annual report, so I hope that you will keep reading. It goes without saying that I’m incredibly proud of the team who’ve worked on all of these projects! 

To summarise, here’s how you can stay up to date with our work and maybe even get involved in studies:

Finally, I am pleased to announce that we will be hosting the UKICER 2026 conference for researchers and teachers in Cambridge on 3 and 4 2026 September. More details will follow on the UKICER website and on the Research Centre website in due course.

The post 2025 highlights from the Raspberry Pi Computing Education Research Centre appeared first on Raspberry Pi Foundation.
Secondary school maths showing that AI systems don’t think

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/secondary-school-maths-showing-that-ai-systems-dont-think/

At a time when many young people are using AI for personal and learning purposes, schools are trying to figure out what to teach about AI and how (find out more in this summer 2025 data about young people’s usage of AI in the UK). One aspect of this is how technical we should get in explaining how AI works, particularly if we want to debunk naive views of the capabilities of the technology, such as that AI tools ‘think’. In this month’s research seminar, we found out how AI contexts can be added to current classroom maths to make maths more interesting and relevant while teaching the core concepts of AI.

Prof. Dr. Martin Frank, Assistant Prof. Dr. Sarah Schönbrodt, Research Associate Stephan Kindler

At our computing education research seminar in July, a group of researchers from the CAMMP (Computational and Mathematical Modeling Program) research project shared their work:

  • Prof. Dr. Martin Frank, Founder of CAMMP (Karlsruhe Institute of Technology (KIT), Germany).
  • Assistant Prof. Dr. Sarah Schönbrodt (University of Salzburg, Austria)
  • Research Associate Stephan Kindler (Karlsruhe Institute of Technology (KIT), Germany)

They talked about how maths already taught in secondary schools can be used to demystify AI. At first glance, this seems difficult to do, as it is often assumed that school-aged learners will not be able to understand how these systems work. This is especially the case for artificial neural networks, which are usually seen as a black box technology — they may be relatively easy to use, but it’s not as easy to understand how they work. Despite this, the Austrian and German team have developed a clear way to explain some of the fundamental elements of AI using school-based maths.

Sarah Schönbrodt started by challenging us to consider that learning maths is an essential part in developing AI skills, as: 

  1. AI systems using machine learning are data-driven and are based on mathematics, especially statistics and data
  2. Authentic machine learning techniques can be used to bring to life existing classroom maths concepts
  3. Real and relevant problems and associated data are available for teachers to use

A set of workshops for secondary maths classrooms

Sarah explained how the CAMMP team have developed a range of teaching and learning materials on AI (and beyond) with an overall goal to “allow students to solve authentic, real and relevant problems using mathematical modeling and computers”. 

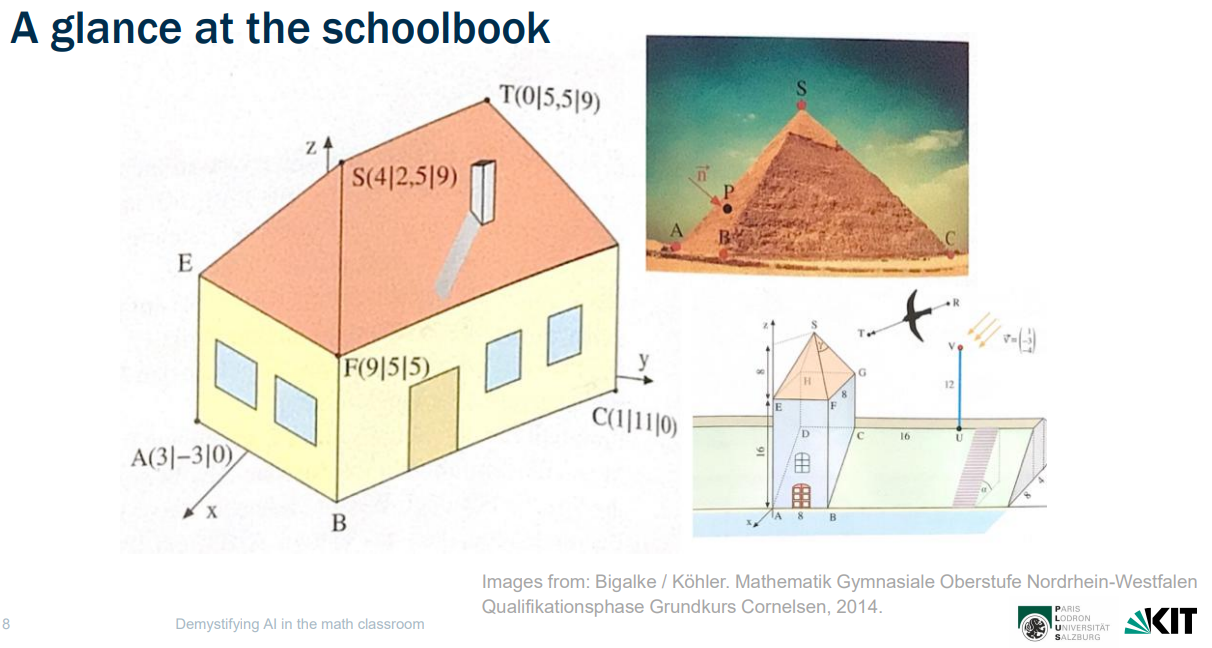
She reflected that much of school maths is set in contexts that are abstract, and may not be very interesting or relevant to students. Therefore, introducing AI-based contexts, which are having a huge impact on society and students’ lives, is both an opportunity to make maths more engaging and also a way to demystify AI.

A glance at the schoolbook diagram
Old-fashioned contexts are often used to teach classroom maths concepts. Those same concepts could be taught using real-world AI contexts. (Slide from the researchers’ presentation.)

Workshops designed and researched by the team include contexts such as privacy in social networks to learn about decision trees, personalised Netflix recommendations to learn about k-nearest neighbour, word predictions to learn about N-Grams, and predicting life expectancy to learn about regression and neural networks.

Learning about classification models: traffic lights and the support vector machine

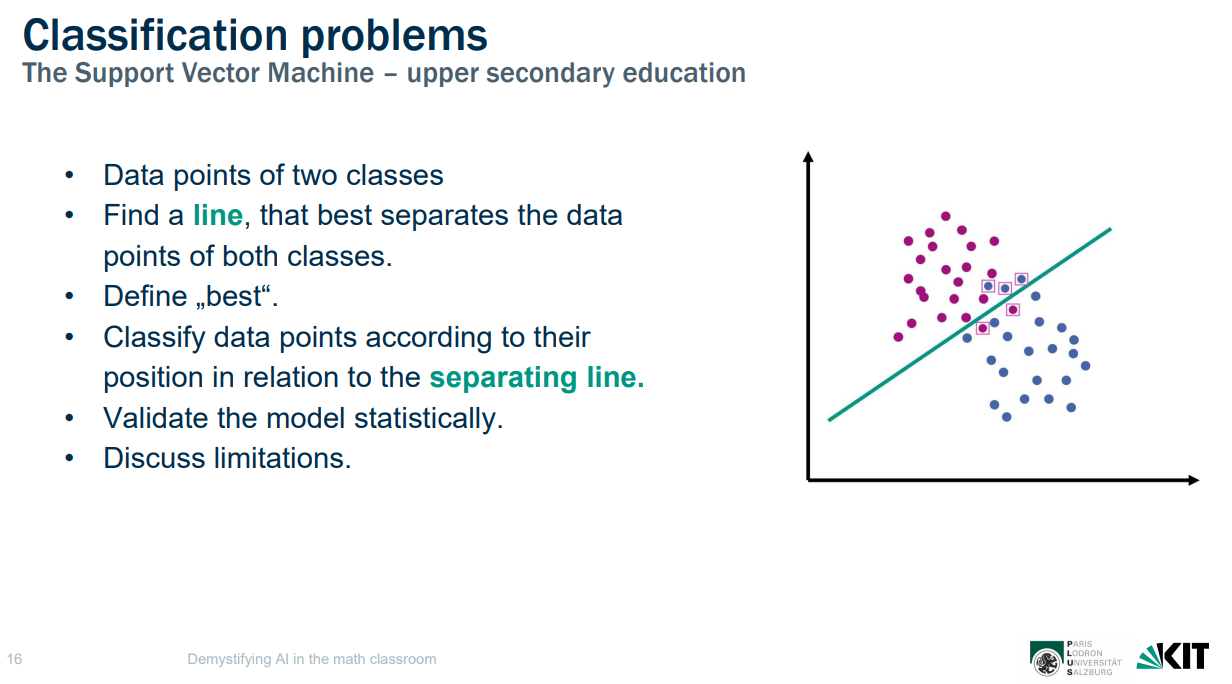
For the seminar, Sarah walked through the steps to learn about support vector machines. This is an upper secondary workshop for students aged 17 to 18 years old. The context of the lesson is an image problem — specifically, classifying the data representing the colours of a simplified traffic light system (two lights to start with) to work out if a traffic light is red or green.

She walked through each of the steps of the maths workshop:

  • Plotting data points of two classes, the representation of green and red traffic lights
  • Finding a line that best separates the data points of both classes
  • Figuring out what best is
  • Classifying the data points in relation to the chosen (separating) line
  • Validating the model statistically to see if it is useful in classifying new data points, including using test data and creating a contingency table (also called a confusion matrix)
  • Discussing limitations, including social and ethical issues
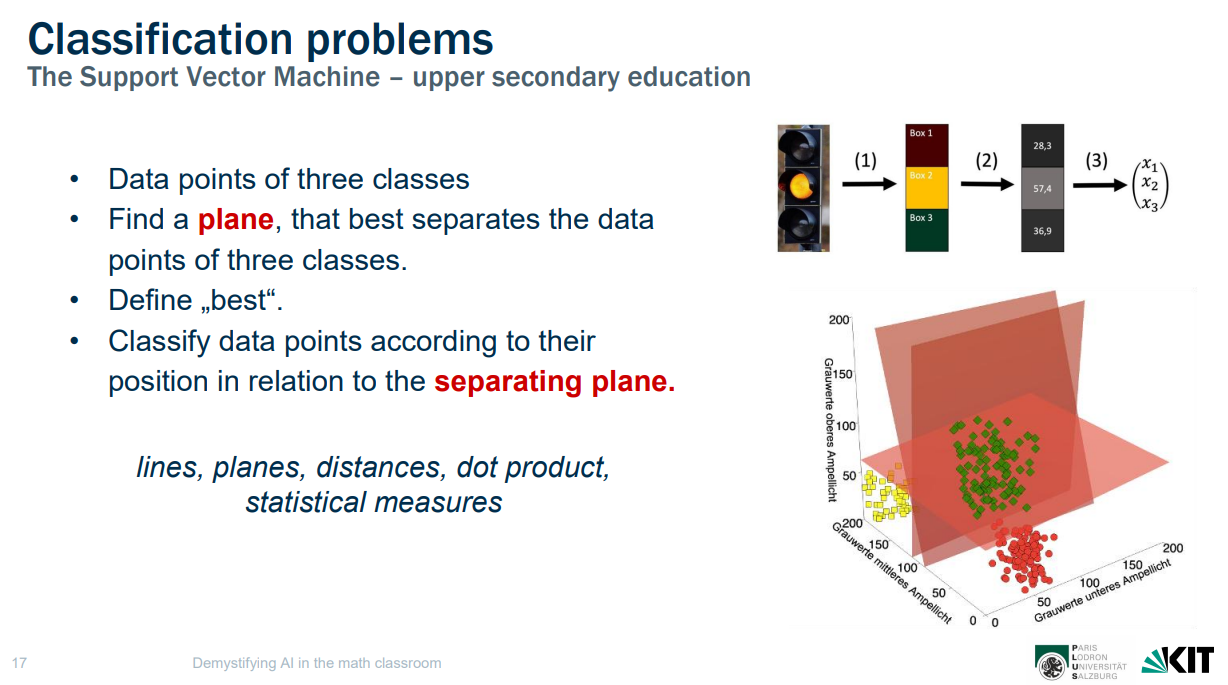
  • Explaining how three traffic lights can be expressed as three-dimensional data by using planes
Classification problems diagram
By classifying green and red traffic light data, students are learning about lines, classifying data, and considering limitations. (Slide from the researchers’ presentation.)

Throughout the presentation, Sarah pointed out where the maths taught was linked to the Austrian and German mathematics curriculum.

Classification problems diagram
Learning about planes, separating planes, and starting to see how data can be represented in vectors. (Slide from the researchers’ presentation.)

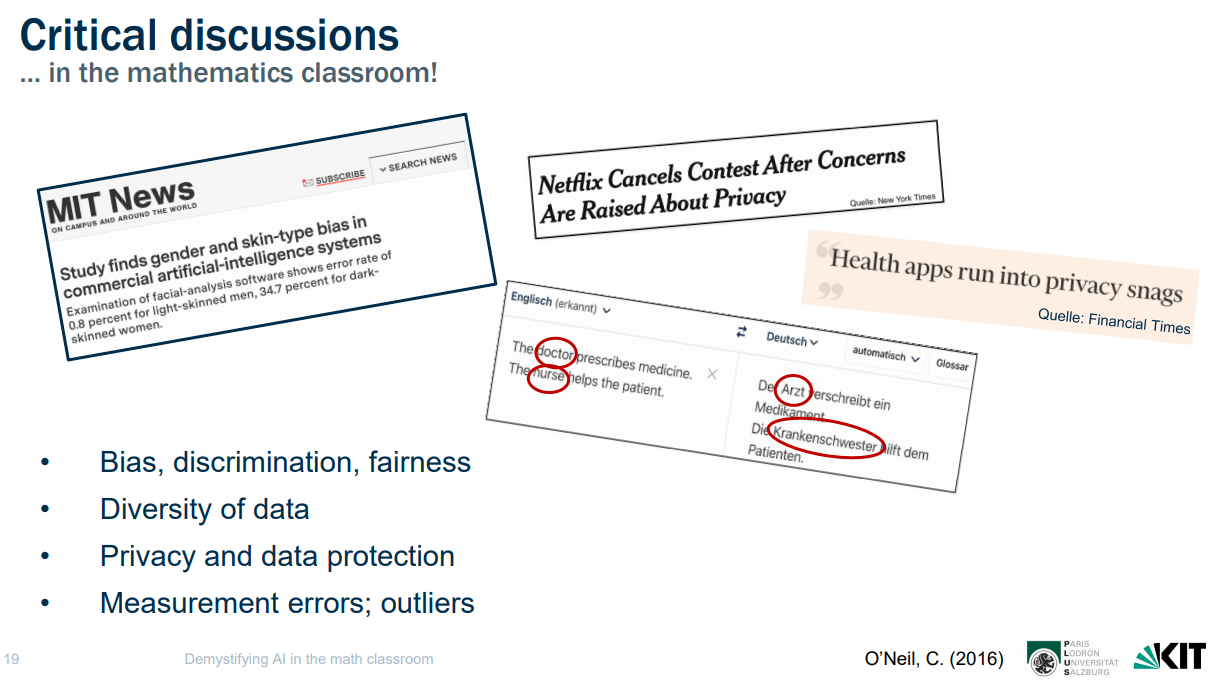
Learning about social and ethical issues

Learning about the social and ethical issues in data-driven systems. (Slide from the researchers’ presentation.)

As well as learning about lines, planes, distances, dot product and statistical measures, learners are also engaged in discussing the social and ethical issues of the approach taken. They are encouraged to think about bias, data diversity, privacy, and the impact of errors on people. For example, if the model wrongly predicts a light as green when it is red, then an autonomous car would run through a red traffic light. This would likely be a bigger consequence than stopping at a green traffic light that was mis-predicted as red. So should the best line reduce this kind of error?

To teach the workshops, Sarah explained they have developed interactive Jupyter notebooks, where no programming skills are needed. Students fill in the gaps of example code, explore simulations, and write their ideas for discussion for the whole class. No software needs to be installed, feedback is direct, and there are in-depth tasks and staggered hints.

Learning about regression models: Weather forecasting and the toy artificial neural network

Stephan went on to introduce artificial neural networks (ANNs), which are the basis of generative AI applications like chatbots and image generation systems. He focused on regression models, such as those used in weather forecasting. 

ANNs are very complex. Therefore, to start to understand the fundamentals of this technology, he introduced a ‘toy ANN’ with one input, three nodes, and one output. A function is performed on the input data at each node. With the toy network, the team wants to tackle a major and common misconception: that students think that ANN systems learn, recognise, see, and understand, when really it’s all just maths.

Tackling misconceptions about ANNs by exploring how they work in a toy version. (Slide from the researchers’ presentation.)

The learning activity starts by looking at one node with one input and one output, and can be described as a mathematical function, with a concatenation of two functions (in this case a linear and activation function). Stephan shared an online simulator that visualises how the toy neural network can be explored as students change two parameters (in this case, weight and bias of the functions). Students then look at the overall network, and the way that the output from the three nodes is combined. Again, they can explore this in the simulator. Students compare simple data about weather prediction to the model, and discover they need more functions — more nodes to better fit the data. The activity helps students learn that ANN systems are just highly adjustable mathematical functions that, by adding nodes, can approximate relationships in a given data set. But the approximation only works in the bounds (intervals) in which data points are given, showing that ANNs do not ‘understand’ or ’know’ — it’s just maths.

Stephen finished by explaining the mutual benefits of AI education and maths education. He suggested maths will enable a deeper understanding of AI, and give students a way to realistically assess the opportunities and risks of AI tools and show them the role that humans have in designing AI systems. He also explained that classroom maths education can benefit from incorporating AI contexts. This approach highlights how maths underpins the design and understanding of everyday systems, supports more effective teaching, and promotes an interdisciplinary way of learning across subjects.

Some personal reflections — which may not be quite right!

I have been researching the teaching of AI and machine learning for around five years now, since before ChatGPT and other similar tools burst on the scene. Since then, I have seen an increasing number of resources to teach about the social and ethical issues of the topic, and there are a bewildering number of learning activities and tools for students to train simple models. There are frameworks for the data lifecycle, and an emerging set of activities to follow to prepare data, compare model types, and deploy simple applications. However, I felt the need to understand and to teach about, at a very simple level, the basic building blocks of data-driven technologies. When I heard the CAMMP team present their work at the AIDEA conference in February 2025, I was entirely amazed and I asked them to present here at our research seminar series. This was a piece of the puzzle that I had been searching for — a way to explain the ‘bottom of the technical stack of fundamental concepts’. The team is taking very complex ideas and reducing them to such an extent that we can use secondary classroom maths to show that AI is not magic and AI systems do not think. It’s just maths. The maths is still hard, and teachers will still need the skills to carefully guide students step by step so they can build a useful mental model. 

Photo of a class of students at computers, in a computer science classroom.

I think we can simplify these ideas further, and create unplugged activities, simulations, and ways for students to explore these basic building blocks of data representation, as well as classification and representing approximations of complex patterns and prediction. I can sense the beginnings of new ideas in computational thinking, though they’re still taking shape. We’re researching these further and will keep you updated.

Finding out more

If you would like to find out more about the CAMMP resources, you can watch the seminar recording, look at the CAMMP website or try out their online materials. For example, the team shared a link to the jupyter notebooks they use to teach the workshops they demonstrated (and others). You can use these with a username of ‘cammp_YOURPSEUDONYM’, where you can set ‘YOURPSEUDONYM’ to any letters, and you can choose any password. They also shared their toy ANN simulation.
The CAMMP team are not the only researchers who are investigating how to teach about AI in maths lessons. You can find a set of other research papers here.

Join our next seminar

In our current seminar series, we’re exploring teaching about AI and data science. Join us at our last seminar of the series on Tuesday, 27 January 2026 from 17:00 to 18:30 GMT to hear Salomey Afua Addo talk about using unplugged approaches to teach about neural networks.

To sign up and take part, click the button below. We’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars page.

The post Secondary school maths showing that AI systems don’t think appeared first on Raspberry Pi Foundation.
How AI shapes your feed: An explainable social media simulator for the classroom

Post Syndicated from Diana Kirby original https://www.raspberrypi.org/blog/how-ai-shapes-your-feed-an-explainable-social-media-simulator-for-the-classroom/

Social media can have a powerful impact on the way we see and experience the world. What we see in our feeds is not random: it is determined by AI-driven systems that collect vast amounts of data, build user profiles, analyse engagement, and generate recommendations. But while young people are prolific users of social media, studies show that many have little understanding of what is happening ‘under the hood’

Henriikka Vartiainen and Matti Tedre from the University of Eastern Finland
Researchers Henriikka Vartiainen and Matti Tedre.

In our September research seminar, we welcomed back Henriikka Vartiainen and Matti Tedre from the University of Eastern Finland. They introduced Somekone, a social media simulator that is designed to help learners understand some of the fundamental processes behind social media platforms. Their team has been developing AI education materials and tools since 2019, including GenAI Teachable Machine, which they presented at our May research seminar.

Collaboration and co-design

Henriikka explained that the development of the Somekone tool emerged from the team’s long-term collaboration with teachers and schools in Finland. They co-developed the tool with the aim of making concepts like data collection, engagement, profiling, recommendations, filter bubbles, and polarisation visible and explainable for students aged 11 to 13 years old.

Photo of three school pupils together looking at a mobile phone.

A four-phase learning model

Henriikka described the pedagogical model that the team follows in all of their AI education interventions. Their goal is not only to support students to develop their understanding of AI concepts, but also to foster ethical awareness and a sense of agency.

  • Phase 1: Contextualisation and familiarisation
    Students begin by discussing their experiences with social media and their initial ideas about how platforms such as TikTok, YouTube, and Instagram work. This activates students’ prior knowledge and helps connect the learning to their own interests. It also enables teachers to uncover any misconceptions the students may have.
  • Phase 2: Exploration
    Students explore their initial ideas by experimenting with the Somekone tool. They discover how different types of data are collected and combined for profiling in a way that connects these new concepts to their own everyday lives.
  • Phase 3: Design and inquiry
    Students explore the Somekone tool more deeply. Teachers guide them through activities where the students analyse, interpret, and discuss the data they can see in the tool. Importantly, the data they are using has all been gathered from their activity on the platform. Students can see how the likes, follows, and comments they and their classmates make change the images they are shown, and this is all real time.
  • Phase 4: Ethical and societal reflection
    Students reflect on what they have learnt and consider the broader impacts of social media. Teachers encourage them to think critically, question the way social media platforms currently work, and imagine alternatives. At the end of the project, students write letters to decision-makers with their suggestions for how social media could better serve children’s interests.

Inside the simulator

Matti then gave a live demonstration of Somekone. Nothing compares to seeing the tool in action, so do check out the video of his demo here!

Students log on to the tool and are presented with an Instagram-style feed of images. They scroll through the feed and like, share, or comment on images that catch their attention or match their interests. For many students this is a very familiar type of environment, and they really enjoy playing with the app!

Four young people sitting at their desks, on their mobile phones.

However, the unique value of Somekone is that it provides students with a real-time view of the way data is collected from every single user interaction, and demonstrates what is done with that data. It also allows students to experiment with a social media tool in the classroom without any data protection issues, as all of the data is stored locally.

Learners explore:

  • Data collection in real time. Working in pairs, one student browses the image feed, while the other watches a live view of the data that the simulator is collecting every time their partner interacts with or simply pauses on a post.
  • Profile building. Somekone shows how all this data accumulates to build a profile. Students watch their profiles developing based on the way they and their classmates are interacting with their feeds.
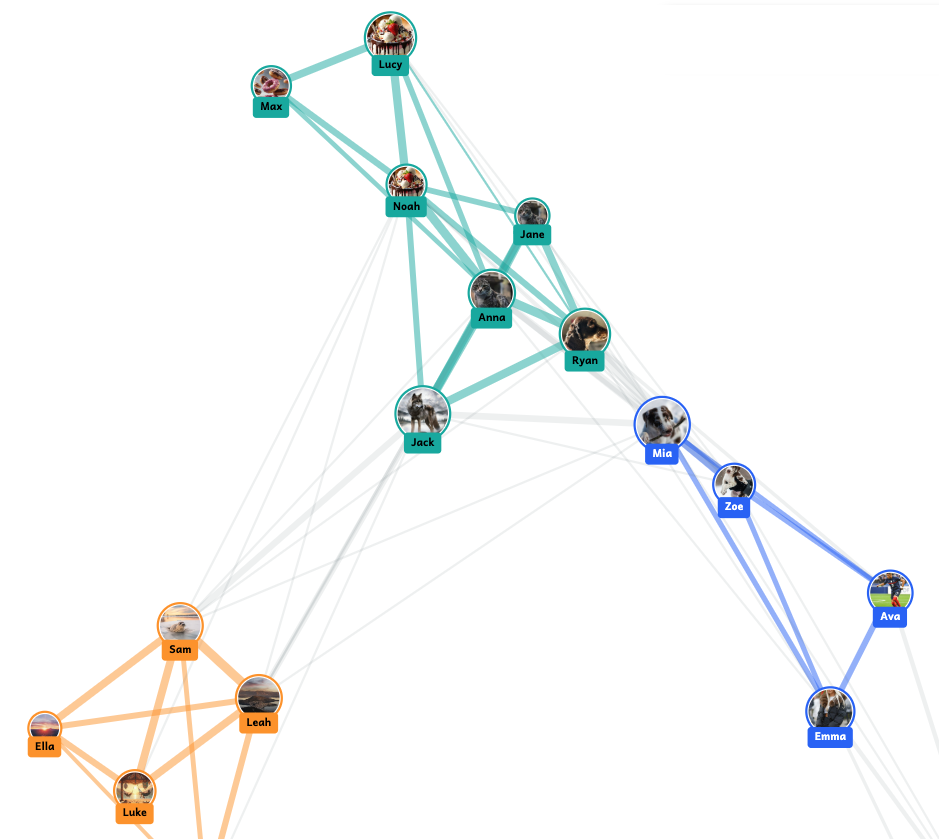
  • Clustering and connections. Students then see how the tool groups profiles to create clusters of users with similar interests. Often friendship groups in the classroom are evident on screen because students sitting next to each other have all chosen to engage with the same things!
The simulator creates clusters of users with similar interests, which update in real time as students interact with posts on their feeds

The simulator creates clusters of users with similar interests, which update in real time as students interact with posts on their feeds

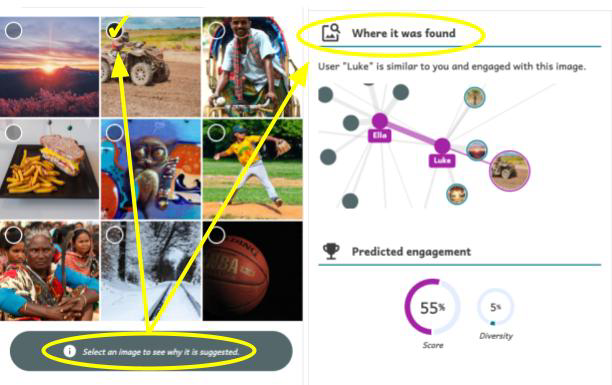
  • Explainable recommendations. A key feature of Somekone is that it provides explanations for why it recommends posts to users. Students learn that recommendations can be based on various things, such as the image’s tag matching the tag on other posts they liked, or the image being popular among other users with similar profiles to theirs. These are the mechanisms that underpin real recommendation systems, but Somekone makes them explicit.
The tool provides an explanation for why each post is recommended

The tool provides an explanation for why each post is recommended

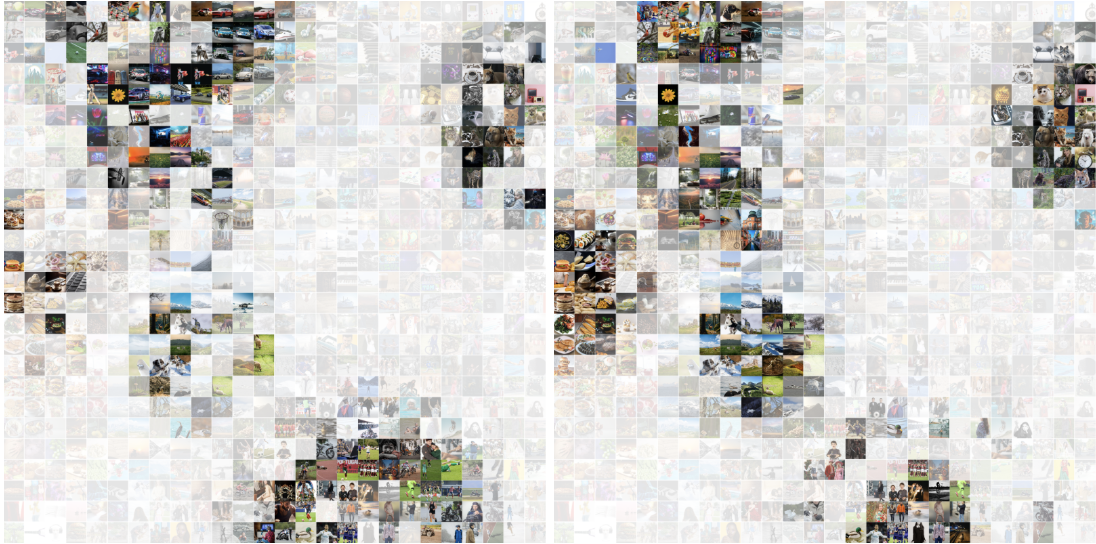
  • Filter bubbles and polarisation. A filter bubble forms when a user only sees social media posts that match their existing interests or beliefs, due to highly personalised recommendation systems. Somekone presents this concept in a visually compelling way through a heatmap showing all the content in the system, with a colour scale indicating which posts are most likely to be shown to a particular user, and which they will never encounter. By comparing different users’ filter bubbles side by side, students start to understand how polarisation can arise. As Matti said: “If our feeds are so different from each other that I never see the pictures that you see and you never see the pictures I see, then […] we don’t even share the same reality”.
Two users’ heatmaps presented side by side, showing their respective filter bubbles

Two users’ heatmaps presented side by side, showing their respective filter bubbles

  • Algorithm settings. A key learning opportunity is that students can adjust the algorithm’s parameters and observe how this changes their feed and their filter bubble. They can choose between personalised or non-personalised recommendations, select how posts are ranked, and decide whether to allow any diversity in the popularity of posts recommended to them. This is key to ‘opening up the box’.

For teachers, the tool has a simple guided interface to make it easy to use in class. There is also a button that teachers can use to pause the app, stopping students from scrolling (much to their dismay!) in order to focus their attention on the teacher when they are explaining concepts.

Evidence of impact

The research team used pre- and post-tests to evaluate what impact the intervention had on students’ understanding of social media mechanisms and on their sense of agency in relation to data. They conducted the post-test a week after the intervention, and then also did a delayed post-test six months later to see whether any changes were sustained. They found:

  • Improved understanding of key concepts. Learners showed statistically significant improvements in identifying different types of data traces and in understanding how data profiling works. They also showed some improvement in grasping recommendation mechanisms.
  • Retention over time. These improvements were generally still evident six months later, particularly in the case of understanding data traces.
  • Stronger sense of agency. The team found that students’ sense of data agency improved after taking part in the intervention. This is really important as students are more likely to want to study a topic further if they have feelings of agency and self-efficacy.

Accessing the tool

The Somekone tool is freely available online — in Finnish, English, German, and French — at somekone.gen-ai.fi. The developer Nick Pope has also made the source code available on GitHub at github.com/knicos/genai-somekone

However, the supporting materials and teacher resources are currently only available in Finnish and the underpinning pedagogies relate to the Finnish context.

Join our next seminar

Join us at our next seminar on Tuesday, 11 November from 17:00 to 18:30 GMT to hear Karl-Emil Bilstrup (Copenhagen University) speak about using the micro:bit to explore machine learning practices. We hope to see you there!

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars page.

The post How AI shapes your feed: An explainable social media simulator for the classroom appeared first on Raspberry Pi Foundation.
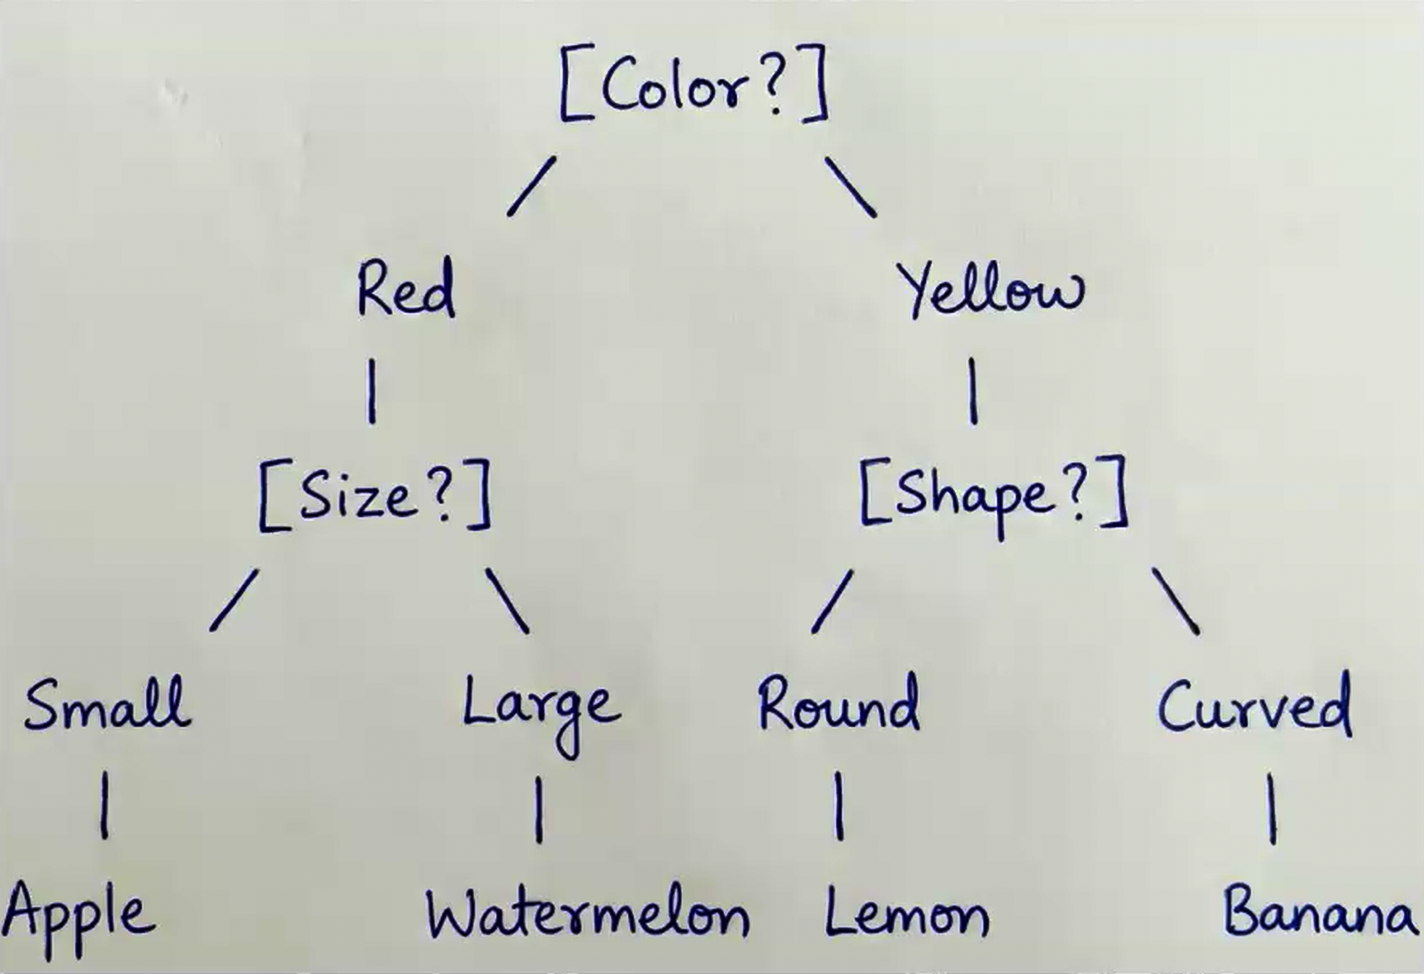
Promoting young people’s agency in the age of AI

Post Syndicated from Claire Johnson original https://www.raspberrypi.org/blog/promoting-young-peoples-agency-in-the-age-of-ai/

Part of teaching young people AI literacy skills is teaching them to critically think about AI, and to design AI applications that address problems they care about. How to do this was the focus of our June research seminar.

An educator helping a learner in the classroom

Working together to design AI

Our June research seminar was delivered by Netta Iivari, Professor in Information Systems at the University of Oulu’s INTERACT Research Unit.

The INTERACT research group focuses on understanding and supporting participatory design, user-centered design, user-driven innovation, and human interaction with technology in everyday life contexts. From this perspective, “users” aren’t considered as passive consumers, but as valuable co-creators and content producers. This calls for different approaches that place emphasis on empowerment and inclusion in designing, shaping, and co-creating information technology in everyday life.

As part of this work, Netta introduced the idea of ‘transformative agency’ — empowering children to believe they can solve problems they care about — and its application in secondary computing education. She showed examples of how to foster young people’s transformative agency within computing, specifically focusing on transdisciplinary approaches to learning about AI and inviting young people to critically analyse and design their futures with AI tools in it.

Netta began by giving an overview of two of the INTERACT Research Unit’s projects: 

  1. The Make a difference (MAD) project (2019–2023) explored critical design with young people, focusing on their emerging designer and maker identities in the context of tackling a significant societal problem — in this case, bullying. 
  2. Children’s transformative agency and emerging technologies for social good (TAKEOVER) (2024–2028), a current project, explores the potential of emerging technologies (artificial intelligence, virtual reality (VR), social robots, etc.) to address societal problems, such as climate change, gender equality, bullying, and discrimination. It focuses on children’s emerging transformative agency and activist identities when engaging with these tools and topics. 
An educator points to an image on a secondary learners computer screen.

Netta explained that these projects give young people an opportunity to begin to address the problems they care about, even though they may be very complex problems. From this problem-solving perspective, children are introduced (or ‘sensitised’) to emerging technologies as tools for social good.

She then went on to outline the key pedagogical approaches that underpin these projects:  

  1. Critical, ethical, empowering design
    This pedagogy draws on critical and speculative design traditions in design research and encourages young people to take a critical perspective towards society, its norms, and the status quo, as part of design thinking. Children consider the ethical values and consequences of their designs. They begin to experience the ways in which engaging in the design process can be empowering and transformative for them, collectively as well as individually. 
  2. Transformative agency of children
    This approach encourages young people to consider their capacity to have agency in the world, by enabling them to envision change and commit to taking action to solve problems that they care about. 
  3. Fostering transformative agency of children in the age of AI
    Transformative agency is achieved when young people engage in ‘expansive learning’ — when they learn something novel, together, and are encouraged to look beyond the confines of school work, the topic, themselves, and the tools available for solving the problem. This approach fosters an active, critical, reflective mindset that encourages children to believe that they can make change and have impact in the world. 

The project design process

The projects follow 3 design phases and include a range of plugged and unplugged activities, as shown in Figure 1.

Figure 1. The project phases

Netta then described in more detail some of the activities that have been used to address these different project phases and the design process involved. For example, to explore what are the problems that children really care about, they are asked to imagine ‘carrying a stone in your pocket for one week, as if it was a magic tool. Where could it be used in your everyday life? What problems could it solve? What problems would you like it to solve and how?’ 

Young people are then introduced to a range of novel technologies, for example, VR headsets, robots, and emulators of AI-driven social media platforms, such as “Somekone”, developed as part of the Generative AI project at the University of Eastern Finland. They deconstruct and reconstruct generative AI tools by prompting large language model chatbots such as ChatGPT, Gemini, Claude, etc. and exploring bias in their outputs. They perform small-scale algorithmic auditing and create mini language models (with Google Colab), using the text in Alice in Wonderland to train their models, and then open datasets (books as text files from Project Gutenberg). In exploring the responses generated, they experience the potential and the limitations of such tools and gain an important understanding of the human activity involved in the development of AI technologies. 

Secondary school age learners in a computing classroom.

Once they have had this ‘sensitising‘ exposure to a range of tools, they then work in groups on a project that makes use of AI to solve the societal problem they have chosen. These problems could encompass a range of topics, such as racism, animal rights, the impact of AI, war, mental health, bullying. The young people are prompted to think about how large language models can be used to solve the problem, or parts of the problem. But importantly, they are also asked to consider the different motives and perspectives of the multiple stakeholders involved in the problem and its solution and whether their model ideas will create new problems when deployed.

They follow the 3 project phases shown in Figure 1 to design and make a range of digital (robots, apps, videos) and non-digital artefacts to solve their problem. Netta emphasised that although it could take 10 weeks or more to implement all the suggested activities, it is also possible to pick and choose individual tasks from the 3 phases to suit available curriculum timescales.

Envisioning and critiquing AI futures

Other project tasks involve: 

  • Envisioning AI futures by imagining that a miracle has happened overnight and the problem has disappeared — what is the result? 
  • Critiquing AI futures by creating best and worst case scenarios of the consequences of the AI systems they design, creating video adverts promoting their AI solutions and anti-adverts, focusing on the possible negative consequences of their prototypes 
  • Fostering action-taking by presenting theatrical performances to showcase how their designs tackle a problem and illustrating the AI-related issues surrounding the topic or by creating activism campaign material to mobilise the school community on the same themes 
Secondary education learners in the classroom

These projects situate learning about data-driven technologies in real-world contexts and promote a transdisciplinary approach, teaching and learning about AI from a problem-solving perspective. 

This perspective conveys important messages to young people — that they do have agency and can take action in the face of many of the world’s problems, that they can and should be active, critical users of the new technologies that surround them, and that these technologies can be used to change the world for good. 

Netta ended the seminar by asking viewers to consider how they could foster transformative agency in the young people they teach and whether or not they consider it to be important in computing education.

Resources relating to the projects can be found at interact.oulu.fi.

Join our next seminar

In our current seminar series, we’re exploring teaching about AI and data science. Join us at our next seminar on Tuesday 14 October from 17:00 to 18:30 GMT to hear Viktoriya Olari talk about data-related concepts and practices for AI education in K–12.

To sign up and take part, click the button below. We’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars page.

The post Promoting young people’s agency in the age of AI appeared first on Raspberry Pi Foundation.
Opening the box: Tools to teach young people about AI

Post Syndicated from Bonnie Sheppard original https://www.raspberrypi.org/blog/opening-the-box-tools-to-teach-young-people-about-ai/

New research by the Alan Turing Institute, published in June, shows that in the UK nearly one in four children aged 8 to 12 is using artificial intelligence (AI) tools like ChatGPT. With learners exploring these tools at such young ages, it’s more urgent than ever to develop teaching resources that help them understand how AI works.

One of the biggest challenges with AI is that it’s hard to tell how these tools function. With a chatbot, you enter a prompt and the tool returns a response, but what happens in between is invisible. For educators, that’s a problem: how can we help young people become thoughtful, creative users of AI tools if the technology feels like a closed box?

In our May research seminar, we welcomed Matti Tedre and Henriikka Vartiainen from the University of Eastern Finland. They’ve been working on how to teach about AI for years and were frustrated with existing educational platforms: many of these are either too complex, raise privacy concerns, or rely on coding skills that not all students (or teachers) have. In response, they created an award-winning, classroom-friendly tool designed to make AI technology more transparent and more hands-on.

A practical way to teach AI in schools

Matti and Henriikka began by discussing the unique challenges of teaching young learners about AI technology. Many students start with “folk theories”, for example, thinking that computers understand language like humans do. These misconceptions can be surprisingly hard to shake.

They also pointed out broader issues:

  • The abstract nature of AI means there are very few research-based approaches to teaching it effectively
  • Mastery of AI concepts requires sustained practice and curricular change, not just a few one-off interventions
  • In countries like Finland, where programming isn’t part of the curriculum, any teaching tool must be no-code to be accessible

To address these challenges, Matti and Henriikka have spent three years co-designing tools and approaches with local schools, teachers, and over 200 students. Their approach is grounded in educational theory and a set of core AI learning principles:

  • No-code for inclusivity: Removing the need for programming lowers the barrier to entry for both teachers and students
  • Learner-centred co-design: Every part of the experience is developed in collaboration with schools to make sure it’s engaging and relevant
  • Working with personal data: Learners create and work with their own data sets, which makes the experience more engaging and personally relevant
  • Integration with school subjects: Integrating AI concepts into other subjects helps to make the uses of AI tools more concrete for learners
  • Focus on specific applications: Rather than teaching about generic ‘AI’, the focus is on specific and understandable applications, such as facial recognition
  • Hands-on experimentation: Practical projects help students understand tricky ideas like bias, fairness, and social impact
  • Collaborative learning: Working together helps students reflect, question, and learn from each other

GenAI Teachable Machine: Opening the box

Frustrated by existing platforms that require programming skills, raise privacy concerns, or don’t allow collaboration, Matti and Henriikka’s team developed GenAI Teachable Machine: a no-code, browser-based tool designed to make key AI concepts tangible. In the central research study, the team used the tool with Finnish students in grade 4–7 (10 to 14 years of age). It’s a great introductory tool that could also be used with younger and older students.

GenAI Teachable Machine is freely available online and maintains a “line of sight”: All important steps are visible to the learner.
GenAI Teachable Machine is freely available online and maintains a “line of sight”: All important steps are visible to the learner

Matti demonstrated how the tool addresses their core AI learning principles with a simple, creative project. Using hand puppets, he trained a model to recognise four distinct classes: a background, a bunny, a calm wolf, and an angry wolf. For each class, he assigned a specific action: a sound, an image, or both. This hands-on process gives students a direct line of sight from the data they might create (visuals of hand puppets) to the final behaviour of the model (outputted sounds and images). They learn about classifiers, training, and confidence levels not as abstract definitions, but as creative tools they can control.

Matti Tedre demonstrating a bunny and wolf recognition model.
Matti Tedre demonstrating a bunny and wolf recognition model

But the learning really starts when things don’t work as expected. Students can easily open their models on their phones with an automatically created QR code and then move around the classroom to test their models. At this point, they quickly notice how fragile AI technology can be. For example, in the case of a simple recognition model trained on specific colours or features, with a change of lighting or a different shirt, the model might fail. These “failures” turn into powerful lessons. For instance, a face-recognition app trained mostly on students with blonde hair might not work well for someone with brown hair — sparking immediate conversations about bias. As Matti put it, students very quickly start asking deep questions. 

In a computing classroom, two girls concentrate on their programming task.

GenAI Teachable Machine also allows students to apply their AI models to the physical world. By connecting to a simple, low-cost robotics kit, students can use their models to control motors, lights, and other actuators. This step into the physical world teaches fundamental concepts that are difficult to grasp in a purely virtual environment. Students learn about causality, as their model’s classifications trigger real, physical actions. They also learn about the need for a world model — an understanding of how the physical world works — and see that they must take responsibility for what happens when their abstract models have real-world consequences.

Examples of students’ robot creations.
Examples of students’ robot creations

By combining a no-code platform with practical, well-designed learning experiences, Matti, Henriikka, and their team are showing what AI education can look like: hands-on, accessible, and grounded in real understanding. Their work is helping students see inside the box, and giving them the tools to think critically about the AI technologies that are becoming part of their everyday lives.

Find out more

If you’re an educator interested in including the topic of AI in your teaching, you can try GenAI Teachable Machine on its official website.

You may also be interested in our own Experience AI resources, which are designed to help you and your learners navigate the fast-moving world of AI and machine learning technologies.

Join us at our next seminar

In September, Matti and his team are returning to discuss other ways to teach young people about AI technologies.

To sign up and take part in the Matti’s seminar on Tues 9 Sept at 17:00–18:30 BST, click the button below. We’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars page.

The post Opening the box: Tools to teach young people about AI appeared first on Raspberry Pi Foundation.
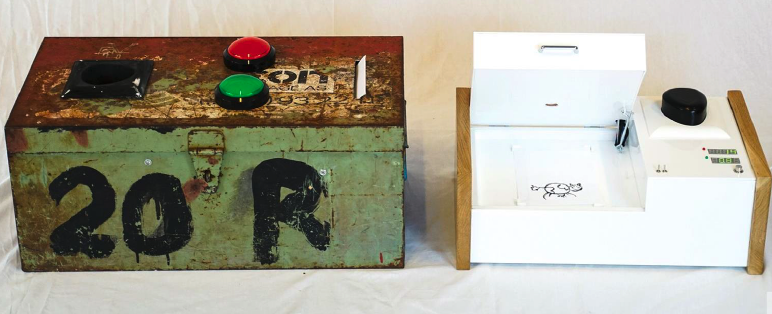
Bringing data science to life for K–12 students with the ‘API Can Code’ curriculum

Post Syndicated from Diana Kirby original https://www.raspberrypi.org/blog/bringing-data-science-to-life-for-k-12-students-with-the-api-can-code-curriculum/

As data and data-driven technologies become a bigger part of everyday life, it’s more important than ever to make sure that young people are given the chance to learn data science concepts and skills.

In our April research seminar, David Weintrop, Rotem Israel-Fishelson, and Peter Moon from the University of Maryland introduced API Can Code, a data science curriculum designed with high school students for high school students. Their talk explored how their innovative work uses real-world data and students’ own experiences and interests to create meaningful, authentic learning experiences in data science.

Quick note for educators: Are you interested in joining our free, exploratory data science education workshop for teachers on 10 July 2025 in Cambridge, UK? Then find out the details here.

David started by explaining the motivation behind the API Can Code project. The team’s goal was not to turn students into future data scientists, but to offer students the data literacy they need to explore and critically engage with a data-driven world. 

The work was also guided by a shared view among leading teachers’ organisations that data science should be taught across all subjects in the K–12 curriculum. It also draws on strong research showing that when educational experiences connect with students’ own lives and interests, it leads to deeper engagement and better learning outcomes.

Reviewing the landscape

To prepare for the design of the curriculum, David, Rotem, and Peter wanted to understand what data science education options already exist for K–12 students. Rotem described how they compared four major K–12 data science curricula and examined different aspects, such as the topics they covered and the datasets they used. Their findings showed that many datasets were quite small in size, and that the datasets used were not always about topics that students were interested in.

A classroom of young learners and a teacher at laptops

The team also looked at 30 data science tools used across different K–12 platforms and analysed what each could do. They found that tools varied in how effective they were and that many lacked accessibility features to support students with diverse learning needs. 

This analysis helped to refine the team’s objective: to create a data science curriculum that students find interesting and that is informed by their values and voices.

Participatory design

To work towards this goal, the team used a methodology called participatory design. This is an approach that actively involves the end users — in this case, high school students — in the design process. During several in-person sessions with 28 students aged 15 to 18 years old, the researchers facilitated low-tech, hands-on activities exploring the students’ identities and interests and how they think about data.

One activity, Empathy Map, involved students working together to create a persona representing a student in their school. They were asked to describe the persona’s daily life, interests, and concerns about technology and data:

The students’ involvement in the design process gave the team a better understanding of young people’s views and interests, which helped create the design of the API Can Code curriculum.

API Can Code: three units, three key tools

Peter provided an overview of the API Can Code curriculum. It follows a three-unit flow covering different concepts and tools in each unit:

  1. Unit 1 introduces students to different types of data and data science terminology. The unit explores the role of data in the students’ daily lives, how use and misuse of data can affect them, different ways of collecting and presenting data, and how to evaluate databases for aspects such as size, recency, and trustworthiness. It also introduces them to RapidAPI, a hub that connects to a wide range of APIs from different providers, allowing students to access real-world data such as Zillow housing prices or Spotify music data.
  2. Unit 2 covers the computing skills used in data science, including the use of programming tools to run efficient data science techniques. Students learn to use EduBlocks, a block-based programming environment where students can draw in JSON files from RapidAPI datasets, and process and filter data without needing a lot of text-based programming skills. The students also compare this approach with manual data processing, which they discover is very slow.
  3. Unit 3 focuses on data analysis, visualisation, and interpretation. Students use CODAP, a web-based interactive data science tool, to calculate summary statistics, create graphs, and perform analyses. CODAP is a user-friendly but powerful platform, making it perfect for students to analyse and visualise their data sets. Students also practise interpreting pre-made graphs and the graphs and statistics that they are creating.

Peter described an example activity carried out by the students, showing how these three units flow together and build both technical skills and an understanding of the real-world uses of data science. Students were tasked with analysing a dataset from Zillow, a property website, to explore the question “How much does a house in my neighbourhood cost?” The images below show the process the students followed, which uses the data science skills and tools from all three units of the curriculum.

Interest-driven learning in action

A central tenet of API Can Code is that students should explore data that matters to them. A diverse range of student interests was identified during the design work, and the curriculum uses these areas of interest, such as music, movies, sports, and animals, throughout the lessons.

The curriculum also features an open-ended final project, where students can choose a research question that is important to them and their lives, and answer it using data science skills.

The team shared two examples of memorable final projects. In one, a student set out to answer the question “Is Jhené Aiko a star?” The student found a publicly available dataset through an API provided by Deezer, a music streaming platform. She wrote a program that retrieved data on the artist’s longevity and collaborations, analysed the data, and concluded that Aiko is indeed a star. What stood out about this project wasn’t just the fact that the student independently defined stardom and answered their research question using real data, but that this was a truly personal, interest-driven project. David noted that the researchers could never have come up with this activity, since they had never previously heard of Jhené Aiko!

Jhené Aiko, an R&B singer-songwriter
Jhené Aiko, an R&B singer-songwriter 
(Photo by Charito Yap, licensed under CC BY-ND 2.0)

Another student’s project analysed data about housing in Washington DC to answer the question “Which ward in DC has the most affordable houses?” Rotem explained that this student was motivated by her family thinking about moving away from the city. She wanted to use her project to persuade her parents to stay by identifying the most affordable ward in DC that they could move to. She was excited by the outcome of her project, and she presented her findings to other students and her parents.

These projects underscore the power of personally important data science projects driven by students’ interests. When students care about the questions they are exploring, they’re more invested in the process and more likely to keep using the skills and concepts they learn.

Resources

API Can Code is available online and completely free to use. Teachers can access lesson plans, tutorial videos, assessment rubrics, and more from the curriculum’s website https://apicancode.umd.edu/. The site also provides resources to support students, including example programs and glossaries.

Join our next seminar

In our current seminar series, we’re exploring teaching about AI and data science. Join us at our next seminar on Tuesday, 17 June from 17:00 to 18:30 BST to hear Netta Iivari (University of Oulu) introduce transformative agency and its importance for children’s computing education in the age of AI.

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars and recordings page.

The post Bringing data science to life for K–12 students with the ‘API Can Code’ curriculum appeared first on Raspberry Pi Foundation.
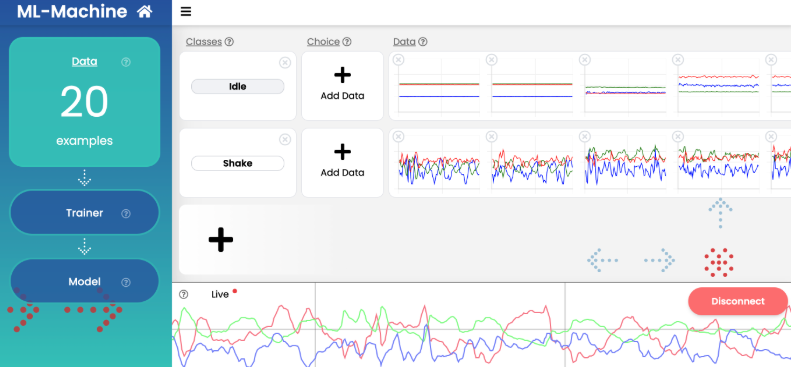
Research insights to help learners develop data awareness

Post Syndicated from Claire Johnson original https://www.raspberrypi.org/blog/research-insights-to-help-learners-develop-data-awareness/

An increasing number of frameworks describe the possible contents of a K–12 artificial intelligence (AI) curriculum and suggest possible learning activities (for example, see the UNESCO competency framework for students, 2024). In our March seminar, Lukas Höper and Carsten Schulte from the Department of Computing Education at Paderborn University in Germany shared with us a unit of work they’ve developed that could inform such a curriculum. At its core, the unit enhances young people’s awareness of how their personal data is used in the data-driven technologies that form part of their everyday lives.

Lukas Höper and Carsten Schulte are part of a larger team who are investigating how to teach school students about data science and Big Data.

Carsten explained that Germany’s informatics (computing) curriculum includes a competency area known as Informatics, People and Society (IPS), which explores the interrelationships between technology, individuals, and society, and how computation influences and is influenced by social, ethical, and cultural factors. However, research has suggested that teachers face several problems in delivering this topic, including:

  • Lack of subject knowledge 
  • Lack of teaching material
  • Lack of integration with other topics in informatics lessons
  • A perception that IPS is the responsibility of other subjects

Some of the findings of that 2007 research were mirrored in a more recent local study in 2025, which found that although there have been some gains in subject knowledge in the interval period, the problems of a lack of teaching material and integration with other computer science (CS) topics persist, with IPS increasingly perceived as the responsibility of the informatics subject area alone. Despite this, within the informatics curriculum, IPS is often the first topic to be dropped when educators face time constraints — and concerns with what and how to assess the topic remain. 

Photo focused on a young person working on a computer in a classroom.

In this context, and as part of a larger, longitudinal project to promote data science teaching in schools called ProDaBi, Carsten and Lukas have been developing, implementing, and evaluating concepts and materials on the topics of data science and AI. Lukas explained the importance of students developing data awareness in the context of the digital systems they use in their everyday lives, such as search engines, streaming services, social media apps, digital assistants, and chatbots, and emphasised the difference between being a user of these systems and a data-aware user. Using the example of image recognition and ‘I am not a robot’ Captcha services, Lukas explained how young people need to develop a data-aware perspective of the secondary purposes of the data collected by these (and other) systems, as well as the more obvious, primary purposes. 

Lukas went on to illustrate the human interaction system model, which presents a continuum of possible different roles, from the student as the user of digital artefacts to the student as the designer of digital artefacts. 

 Figure 1. Different roles in interactions with data-driven technologies
 Figure 1. Different roles in interactions with data-driven technologies

To become data-aware users of digital artefacts, students need to be able to understand and reflect on those digital artefacts. Only then can they proceed to become responsible designers of digital artefacts. However, when surveyed, some students were only moderately interested in engaging with the inner workings of the digital technologies they use in their everyday lives. Many students prefer to use the systems and are less interested in how they process data. 

The explanatory model approach in computing education

Lukas explained how students often become more interested in data-driven technologies when learning about them with explanatory models. Such models can foster data awareness, giving students a different perspective of data-driven technologies and helping them become more empowered users of them. 

To illustrate, Lukas gave the example of an explanatory model about the role of data in digital systems. Such a model can be used to introduce the idea that data is explicitly and implicitly collected in the interaction between the user and the technology, and used for primary and secondary purposes. 

The four parts of the explanatory model.
Figure 2. The four parts of the explanatory model

Lukas then introduced two teaching units that were developed for use with middle school children to evaluate the success of the explanatory model approach in computing education. The first unit explores location data collected by mobile phone networks and the second features recommendation systems used by movie streaming services such as Netflix and Amazon Prime.

Taking the second unit as their focus, Lukas and Carsten outlined the four parts of the explanatory model approach: 

Part 1

The teaching unit begins by introducing recommendation systems and asking students to think about what a streaming service is, how a personalised start page is constructed, and how personal recommendations might be generated. Students then complete an unplugged activity to simulate the process of making movie recommendations for a peer:

Task 1: Students write down movie recommendations for another student. 

Task 2: They then ask each other questions (they collect data). 

Task 3: They write down revised movie recommendations.

Task 4: They share and evaluate their recommendations.  

Task 5: Together they reflect on which collected data was helpful in this exercise and what kind of data a recommendation system might collect. This reflection introduces the concepts of explicit and implicit data collection. 

Part 2

In part 2, students are given a prepared Jupyter Notebook, which allows them to explore a simulation of a recommendation system. Students rate movies and receive personal recommendations. They reconstruct a data model about users, using the idea of collaborative filtering with the k-nearest neighbours algorithm (see Figure 3). 

Figure 3. Data model of movie ratings

Part 3

In part 3, the concepts of primary and secondary purposes for data collection are introduced. Students discuss examples of secondary purposes such as personalised paywalls for movies that can be purchased, and subscriptions based on the predictions of future behaviour. The discussion includes various topics about individual and societal issues (e.g. filter bubbles, behaviour engineering, information asymmetry, and responsible development of data-driven technologies). 

Part 4

Finally, students use the explanatory model as an ‘analytical lens’. They choose other examples from their everyday lives of technologies that implement recommendation systems and analyse these examples, assessing the data practices involved. Students present their results in class and discuss their role in these situations and possible actions they can take to become more empowered, data-aware users.

Uses of explanatory models

Using the explanatory model is one approach to make the Informatics, People and Society strand of the German informatics curriculum more engaging for students, and addresses some of the problems teachers identify with delivering this competency area. 

In presenting the idea of the explanatory model, Carsten and Lukas emphasised that the model in use delivers content as well as functioning as a tool to design teaching content. In the example above, we see how the explanatory model introduces the concepts of:

  1. Explicit and implicit data collection
  2. Primary and secondary purposes of that data 
  3. Data models 

The explanatory model framework can also be used as a focus for academic research in computing education. For example, further research is needed to evaluate if explanatory models are appropriate or ‘correct’ models and to determine the extent to which they are useful in computing education. 

In summary, an explanatory model provides a specific perspective on and explanation of particular computing concepts and digital artefacts. In the example given here, the model focuses on the role of data in a recommender system. Explanatory models are representations of concepts, artefacts, and socio-technical systems, but can also serve as tools to support teaching and learning processes and research in computing education. 

Figure 4. Overview of the perspectives of explanatory models
Figure 4. Overview of the perspectives of explanatory models. Click to enlarge.

The teaching units referred to above are published on www.prodabi.de (in German and English). 

See the background paper to the seminar, called ‘Learning an explanatory model of data-driven technologies can lead to empowered behaviour: A mixed-methods study in K-12 Computing education’.

You can also view the paper describing the development of the explanatory model approach, called ‘New perspectives on the future of Computing education: Teaching and learning explanatory models’.

Join our next seminar

In our current seminar series, we’re exploring teaching about AI and data science. Join us at our next seminar on Tuesday 13 May at 17:00–18:30 BST to hear Henriikka Vartiainen and Matti Tedre (University of Eastern Finland) discuss how to empower students by teaching them how to develop AI and machine learning (ML) apps without code in the classroom.

To sign up and take part in our research seminars, click below:

You can also view the schedule of our upcoming seminars, and catch up on past seminars on our previous seminars and recordings page.

The post Research insights to help learners develop data awareness appeared first on Raspberry Pi Foundation.
Supporting teachers to integrate AI in K–12 CS education

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/supporting-teachers-to-integrate-ai-in-k-12-cs-education/

Teaching about artificial intelligence (AI) is a growing challenge for educators around the world. In our current seminar series, we are gaining insights from international computing education researchers on how to teach about AI and data science in the classroom. In our second seminar, Franz Jetzinger from the Technical University of Munich, Germany, presented his work on supporting teachers to integrate AI into their classrooms. Franz brings a wealth of relevant experience to his research as an accomplished textbook author and K–12 computer science teacher.

A photo of Franz Jetzinger in a library.

Franz started by demonstrating how widespread AI systems and technologies are becoming. He argued that embedding lessons about AI in the classroom presents three challenges: 

  1. What to teach (defining AI and learning content)
  2. How to teach (i.e. appropriate pedagogies)
  3. How to prepare teachers (i.e. effective professional development) 

As various models and frameworks for teaching about AI already exist, Franz’s research aims to address the second and third challenges — there is a notable lack of empirical evidence integrating AI in K–12 settings or teacher professional development (PD) to support teachers.

Using professional development to help prepare teachers

In Bavaria, computer science (CS) has been a compulsory high school subject for over 20 years. However, a recent update has brought compulsory CS lessons (including AI) to Year 11 students (15–16 years old). Competencies targeted in the new curriculum include defining AI, explaining the functionality of different machine learning algorithms, and understanding how artificial neurons work.

Two students are seated at a desk, collaborating on a computing task.

To help prepare teachers to effectively teach this new curriculum and about AI, Franz and colleagues derived a set of core competencies to be used along with existing frameworks (e.g. the Five Big Ideas of AI) and the Bavarian curriculum. The PD programme Franz and colleagues developed was shaped by a set of key design principles:

  1. Blended learning: A blended format was chosen to address the need for scalability and limited resources and to enable self-directed and active learning 
  2. Dual-level pedagogy (or ‘pedagogical double-decker’): Teachers were taught with the same materials to be used in the classroom to aid familiarity
  3. Advanced organiser: A broad overview document was created to support teachers learning new topics 
  4. Moodle: An online learning platform was used to enable collaboration and communication via a MOOC (massive open online course)

Analysing the effectiveness of the PD programme

Over 300 teachers attended the MOOC, which had an introductory session beforehand and a follow-up workshop. The programme’s effectiveness was evaluated with a pre/post assessment where teachers completed a survey of 15 closed, multiple-choice questions on their AI competencies and knowledge. Pre/post comparisons showed teachers’ scores improved significantly having taken part in the PD. This is surprising as a large proportion of participants achieved high pre-scores, indicating a highly motivated cohort with notable prior experience teaching about AI.

Additionally, a group of teachers (n=9) were invited to give feedback on which aspects of the PD programme they felt contributed to the success of implementing the curriculum in the classroom. They reported that the PD programme supported content knowledge and pedagogical content knowledge well, but they required additional support to design suitable learning assessments.

The design of the professional development programme

Using action research to aid AI teaching 

A separate strand of Franz’s research focuses on the other key challenge of how to effectively teach about AI. Franz engaged teachers (n=14) in action research, a method whereby teachers engage in classroom-based research projects. The project explored what topic-specific difficulties students faced during the lessons and how teachers adapted their teaching to overcome these challenges.

The AI curriculum in Bavaria

Findings revealed that students struggled with determining whether AI would benefit certain tasks (e.g. object recognition, text-to-speech) or not (e.g. GPS positioning, sorting data). Franz and colleagues reasoned that students were largely not aware of how AI systems deal with uncertainty and overestimated their capabilities. Therefore, an important step in teaching students about AI is defining ‘what an AI problem is’. 

A teenager learning computer science.

Similarly, students struggled with distinguishing between rule-based and data-driven approaches, believing in some cases that a trained model becomes ‘rule-based’ or that all data models are data-driven. Students also struggled with certain data science concepts, such as hyperparameter, overfitting and underfitting, and information gain. Franz’s team argue that the chosen tool, Orange Data Mining, did not provide an appropriate scaffold for encountering these concepts. 

Finally, teachers found challenges in bringing real-world examples into the classroom, including the use of reinforcement learning and neural networks. Franz and colleagues reasoned that focusing on the function of neural networks, as opposed to their structure, would aid student understanding. The use of high-quality (i.e. well-prepared) real-world data sets was also suggested as a strategy for bridging theoretical ideas with practical examples. 

Addressing the challenges of teaching AI

Franz’s research provides important insights into the discipline-specific challenges educators face when introducing AI into the classroom. It also underscores the importance of appropriate professional development and age-appropriate and research-informed materials and tools to support students engaging with ideas about AI, data science, and machine learning.

Students sitting in a lecture at a university.

Further reading and resources

If you are interested in reading more about Franz’s work on teacher professional development, you can read his paper on a scalable professional development offer for computer science teachers or you can learn more about his research group here.

Join our next seminar

In our current seminar series, we are exploring teaching about AI and data science. Join us at our next seminar on Tuesday 8 April at 17:00–18:30 BST to hear David Weintrop, Rotem Israel-Fishelson, and Peter F. Moon from the University of Maryland introduce ‘API Can Code’, an interest-driven data science curriculum for high-school students.

To sign up and take part in the seminar, click the button below; we will then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

The post Supporting teachers to integrate AI in K–12 CS education appeared first on Raspberry Pi Foundation.
Integrating generative AI into introductory programming classes

Post Syndicated from Bonnie Sheppard original https://www.raspberrypi.org/blog/integrating-generative-ai-into-introductory-programming-classes/

Generative AI (GenAI) tools like GitHub Copilot and ChatGPT are rapidly changing how programming is taught and learnt. These tools can solve assignments with remarkable accuracy. GPT-4, for example, scored an impressive 99.5% on an undergraduate computer science exam, compared to Codex’s 78% just two years earlier. With such capabilities, researchers are shifting from asking, “Should we teach with AI?” to “How do we teach with AI?”

Photo of Leo Porter (UC San Diego)
Leo Porter from UC San Diego
Photo of Daniel Zingaro (University of Toronto)
Daniel Zingaro from the University of Toronto

Leo Porter and Daniel Zingaro have spearheaded this transformation through their groundbreaking undergraduate programming course. Their innovative curriculum integrates GenAI tools to help students tackle complex programming tasks while developing critical thinking and problem-solving skills.

Leo and Daniel presented their work at the Raspberry Pi Foundation research seminar in December 2024. During the seminar, it became clear that much could be learnt from their work, with their insights having particular relevance for teachers in secondary education thinking about using GenAI in their programming classes

Practical applications in the classroom

In 2023, Leo and Daniel introduced GitHub Copilot in their introductory programming  CS1-LLM course at UC San Diego with 550 students. The course included creative, open-ended projects that allowed students to explore their interests while applying the skills they’d learnt. The projects covered the following areas:

  • Data science: Students used Kaggle datasets to explore questions related to their fields of study — for example, neuroscience majors analysed stroke data. The projects encouraged interdisciplinary thinking and practical applications of programming.
  • Image manipulation: Students worked with the Python Imaging Library (PIL) to create collages and apply filters to images, showcasing their creativity and technical skills.
  • Game development: A project focused on designing text-based games encouraged students to break down problems into manageable components while using AI tools to generate and debug code.

Students consistently reported that these projects were not only enjoyable but also responsible for deepening their understanding of programming concepts. A majority (74%) found the projects helpful or extremely helpful for their learning. One student noted that.

Programming projects were fun and the amount of freedom that was given added to that. The projects also helped me understand how to put everything that we have learned so far into a project that I could be proud of.

Core skills for programming with Generative AI

Leo and Daniel emphasised that teaching programming with GenAI involves fostering a mix of traditional and AI-specific skills.

Infographic highlighting a workflow when writing software with Copilot.
Writing software with GenAI applications, such as Copilot, needs to be approached differently to traditional programming tasks

Their approach centres on six core competencies:

  • Prompting and function design: Students learn to articulate precise prompts for AI tools, honing their ability to describe a function’s purpose, inputs, and outputs, for instance. This clarity improves the output from the AI tool and reinforces students’ understanding of task requirements.
  • Code reading and selection: AI tools can produce any number of solutions, and each will be different, requiring students to evaluate the options critically. Students are taught to identify which solution is most likely to solve their problem effectively.
  • Code testing and debugging: Students practise open- and closed-box testing, learning to identify edge cases and debug code using tools like doctest and the VS Code debugger.
  • Problem decomposition: Breaking down large projects into smaller functions is essential. For instance, when designing a text-based game, students might separate tasks into input handling, game state updates, and rendering functions.
  • Leveraging modules: Students explore new programming domains and identify useful libraries through interactions with Copilot. This prepares them to solve problems efficiently and creatively.

Ethical and metacognitive skills: Students engage in discussions about responsible AI use and reflect on the decisions they make when collaborating with AI tools.

Graphic depicting students' confidence levels regarding their programming skills and their use of Generative AI tools.

Adapting assessments for the AI era

The rise of GenAI has prompted educators to rethink how they assess programming skills. In the CS1-LLM course, traditional take-home assignments were de-emphasised in favour of assessments that focused on process and understanding.

Table highlighting the different types of assessments involved in Leo and Daniel's course.
Leo and Daniel chose several types of assessments — some involved having to complete programming tasks with the help of GenAI tools, while others had to be completed without.
  • Quizzes and exams: Students were evaluated on their ability to read, test, and debug code — skills critical for working effectively with AI tools. Final exams included both tasks that required independent coding and tasks that required use of Copilot.
  • Creative projects: Students submitted projects alongside a video explanation of their process, emphasising problem decomposition and testing. This approach highlighted the importance of critical thinking over rote memorisation.

Challenges and lessons learnt

While Leo and Daniel reported that the integration of AI tools into their course has been largely successful, it has also introduced challenges. Surveys revealed that some students felt overly dependent on AI tools, expressing concerns about their ability to code independently. Addressing this will require striking a balance between leveraging AI tools and reinforcing foundational skills.

Additionally, ethical concerns around AI use, such as plagiarism and intellectual property, must be addressed. Leo and Daniel incorporated discussions about these issues into their curriculum to ensure students understand the broader implications of working with AI technologies.

A future-oriented approach

Leo and Daniel’s work demonstrates that GenAI can transform programming education, making it more inclusive, engaging, and relevant. Their course attracted a diverse cohort of students, as well as students traditionally underrepresented in computer science — 52% of the students were female and 66% were not majoring in computer science — highlighting the potential of AI-powered learning to broaden participation in computer science.

A girl in a university computing classroom.

By embracing this shift, educators can prepare students not just to write code but to also think critically, solve real-world problems, and effectively harness the AI innovations shaping the future of technology.

If you’re an educator interested in using GenAI in your teaching, we recommend checking out Leo and Daniel’s book, Learn AI-Assisted Python Programming, as well as their course resources on GitHub. You may also be interested in our own Experience AI resources, which are designed to help educators navigate the fast-moving world of AI and machine learning technologies.

Join us at our next online seminar on 11 March

Our 2025 seminar series is exploring how we can teach young people about AI technologies and data science. At our next seminar on Tuesday, 11 March at 17:00–18:00 GMT, we’ll hear from Lukas Höper and Carsten Schulte from Paderborn University. They’ll be discussing how to teach school students about data-driven technologies and how to increase students’ awareness of how data is used in their daily lives.

To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

The post Integrating generative AI into introductory programming classes appeared first on Raspberry Pi Foundation.

Teaching about AI in K–12 education: Thoughts from the USA

Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/teaching-about-ai-in-k-12-education-thoughts-from-the-usa/

As artificial intelligence continues to shape our world, understanding how to teach about AI has never been more important. Our new research seminar series brings together educators and researchers to explore approaches to AI and data science education. In the first seminar, we welcomed Shuchi Grover, Director of AI and Education Research at Looking Glass Ventures. Shuchi began by exploring the theme of teaching using AI, then moved on to discussing teaching about AI in K–12 (primary and secondary) education. She emphasised that it is crucial to teach about AI before using it in the classroom, and this blog post will focus on her insights in this area.

Shuchi Grover gave an insightful talk discussing how to teach about AI in K–12 education.

An AI literacy framework

From her research, Shuchi has developed a framework for teaching about AI that is structured as four interlocking components, each representing a key area of understanding:

  • Basic understanding of AI, which refers to foundational knowledge such as what AI is, types of AI systems, and the capabilities of AI technologies
  • Ethics and human–AI relationship, which includes the role of humans in regard to AI, ethical considerations, and public perceptions of AI
  • Computational thinking/literacy, which relates to how AI works, including building AI applications and training machine learning models
  • Data literacy, which addresses the importance of data, including examining data features, data visualisation, and biases

This framework shows the multifaceted nature of AI literacy, which involves an understanding of both technical aspects and ethical and societal considerations. 

Shuchi’s framework for teaching about AI includes four broad areas.

Shuchi emphasised the importance of learning about AI ethics, highlighting the topic of bias. There are many ways that bias can be embedded in applications of AI and machine learning, including through the data sets that are used and the design of machine learning models. Shuchi discussed supporting learners to engage with the topic through exploring bias in facial recognition software, sharing activities and resources to use in the classroom that can prompt meaningful discussion, such as this talk by Joy Buolamwini. She also highlighted the Kapor Foundation’s Responsible AI and Tech Justice: A Guide for K–12 Education, which contains questions that educators can use with learners to help them to carefully consider the ethical implications of AI for themselves and for society. 

Computational thinking and AI

In computer science education, computational thinking is generally associated with traditional rule-based programming — it has often been used to describe the problem-solving approaches and processes associated with writing computer programs following rule-based principles in a structured and logical way. However, with the emergence of machine learning, Shuchi described a need for computational thinking frameworks to be expanded to also encompass data-driven, probabilistic approaches, which are foundational for machine learning. This would support learners’ understanding and ability to work with the models that increasingly influence modern technology.

A group of young people and educators smiling while engaging with a computer.

Example activities from research studies

Shuchi shared that a variety of pedagogies have been used in recent research projects on AI education, ranging from hands-on experiences, such as using APIs for classification, to discussions focusing on ethical aspects. You can find out more about these pedagogies in her award-winning paper Teaching AI to K-12 Learners: Lessons, Issues and Guidance. This plurality of approaches ensures that learners can engage with AI and machine learning in ways that are both accessible and meaningful to them.

Research projects exploring teaching about AI and machine learning have involved a range of different approaches.

Shuchi shared examples of activities from two research projects that she has led:

  • CS Frontiers engaged high school students in a number of activities involving using NetsBlox and accessing real-world data sets. For example, in one activity, students participated in data science activities such as creating data visualisations to answer questions about climate change. 
  • AI & Cybersecurity for Teens explored approaches to teaching AI and machine learning to 13- to 15-year-olds through the use of cybersecurity scenarios. The project aimed to provide learners with insights into how machine learning models are designed, how they work, and how human decisions influence their development. An example activity guided students through building a classification model to analyse social media accounts to determine whether they may be bot accounts or accounts run by a human.
A screenshot from an activity to classify social media accounts 

Closing thoughts

At the end of her talk, Shuchi shared some final thoughts addressing teaching about AI to K–12 learners: 

  • AI learning requires contextualisation: Think about the data sets, ethical issues, and examples of AI tools and systems you use to ensure that they are relatable to learners in your context.
  • AI should not be a solution in search of a problem: Both teachers and learners need to be educated about AI before they start to use it in the classroom, so that they are informed consumers.

Join our next seminar

In our current seminar series, we are exploring teaching about AI and data science. Join us at our next seminar on Tuesday 11 March at 17:00–18:30 GMT to hear Lukas Höper and Carsten Schulte from Paderborn University discuss supporting middle school students to develop their data awareness. 

To sign up and take part in the seminar, click the button below — we will then send you information about joining. We hope to see you there.

I want to join the next seminarThe schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

The post Teaching about AI in K–12 education: Thoughts from the USA appeared first on Raspberry Pi Foundation.
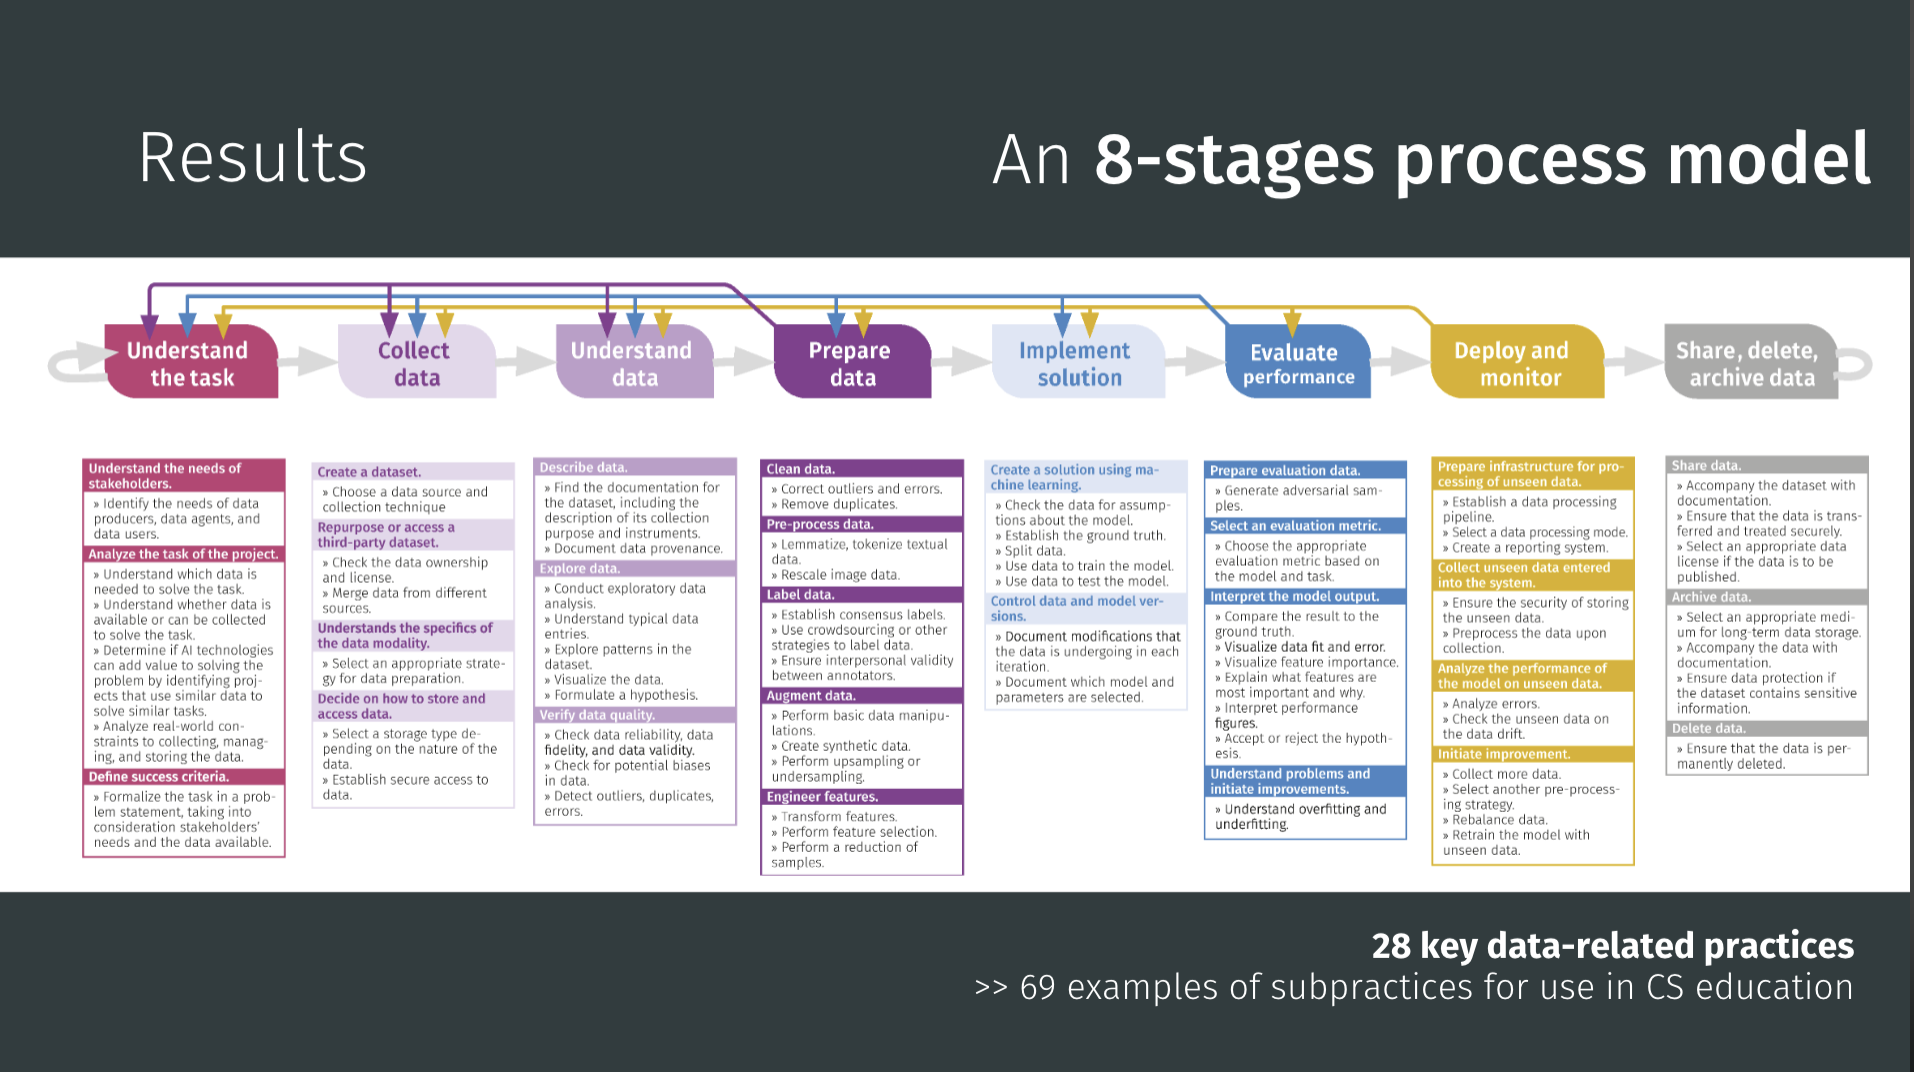
How can we teach students about AI and data science? Join our 2025 seminar series to learn more about the topic

Post Syndicated from Jane Waite original https://www.raspberrypi.org/blog/how-can-we-teach-students-about-ai-and-data-science-2025-seminar-series/

AI, machine learning (ML), and data science infuse our daily lives, from the recommendation functionality on music apps to technologies that influence our healthcare, transport, education, defence, and more.

What jobs will be affected by AL, ML, and data science remains to be seen, but it is increasingly clear that students will need to learn something about these topics. There will be new concepts to be taught, new instructional approaches and assessment techniques to be used, new learning activities to be delivered, and we must not neglect the professional development required to help educators master all of this. 

An educator is helping a young learner with a coding task.

As AI and data science are incorporated into school curricula and teaching and learning materials worldwide, we ask: What’s the research basis for these curricula, pedagogy, and resource choices?

In 2024, we showcased researchers who are investigating how AI can be leveraged to support the teaching and learning of programming. But in 2025, we look at what should be taught about AI, ML, and data science in schools and how we should teach this. 

Our 2025 seminar speakers — so far!

We are very excited that we have already secured several key researchers in the field. 

On 21 January, Shuchi Grover will kick off the seminar series by giving an important overview of AI in the K–12 landscape, including developing both AI literacy and AI ethics. Shuchi will provide concrete examples and recently developed frameworks to give educators practical insights on the topic.

Our second session will focus on a teacher professional development (PD) programme to support the introduction of AI in Upper Bavarian schools. Franz Jetzinger from the Technical University of Munich will summarise the PD programme and share how teachers implemented the topic in their classroom, including the difficulties they encountered.

Again from Germany, Lukas Höper from Paderborn University, with Carsten Schulte will describe important research on data awareness and introduce a framework that is likely to be key for learning about data-driven technology. The pair will talk about the Data Awareness Framework and how it has been used to help learners explore, evaluate, and be empowered in looking at the role of data in everyday applications.  

Our April seminar will see David Weintrop from the University of Maryland introduce, with his colleagues, a data science curriculum called API Can Code, aimed at high-school students. The group will highlight the strategies needed for integrating data science learning within students’ lived experiences and fostering authentic engagement.

Later in the year, Jesús Moreno-Leon from the University of Seville will help us consider the  thorny but essential question of how we measure AI literacy. Jesús will present an assessment instrument that has been successfully implemented in several research studies involving thousands of primary and secondary education students across Spain, discussing both its strengths and limitations.

What to expect from the seminars

Our seminars are designed to be accessible to anyone interested in the latest research about AI education — whether you’re a teacher, educator, researcher, or simply curious. Each session begins with a presentation from our guest speaker about their latest research findings. We then move into small groups for a short discussion and exchange of ideas before coming back together for a Q&A session with the presenter. 

An educator is helping two young learners with a coding task.

Attendees of our 2024 series told us that they valued that the talks “explore a relevant topic in an informative way“, the “enthusiasm and inspiration”, and particularly the small-group discussions because they “are always filled with interesting and varied ideas and help to spark my own thoughts”. 

The seminars usually take place on Zoom on the first Tuesday of each month at 17:00–18:30 GMT / 12:00–13:30 ET / 9:00–10:30 PT / 18:00–19:30 CET. 

You can find out more about each seminar and the speakers on our upcoming seminar page. And if you are unable to attend one of our talks, you can watch them from our previous seminar page, where you will also find an archive of all of our previous seminars dating back to 2020.

How to sign up

To attend the seminars, please register here. You will receive an email with the link to join our next Zoom call. Once signed up, you will automatically be notified of upcoming seminars. You can unsubscribe from our seminar notifications at any time.

We hope to see you at a seminar soon!

The post How can we teach students about AI and data science? Join our 2025 seminar series to learn more about the topic appeared first on Raspberry Pi Foundation.
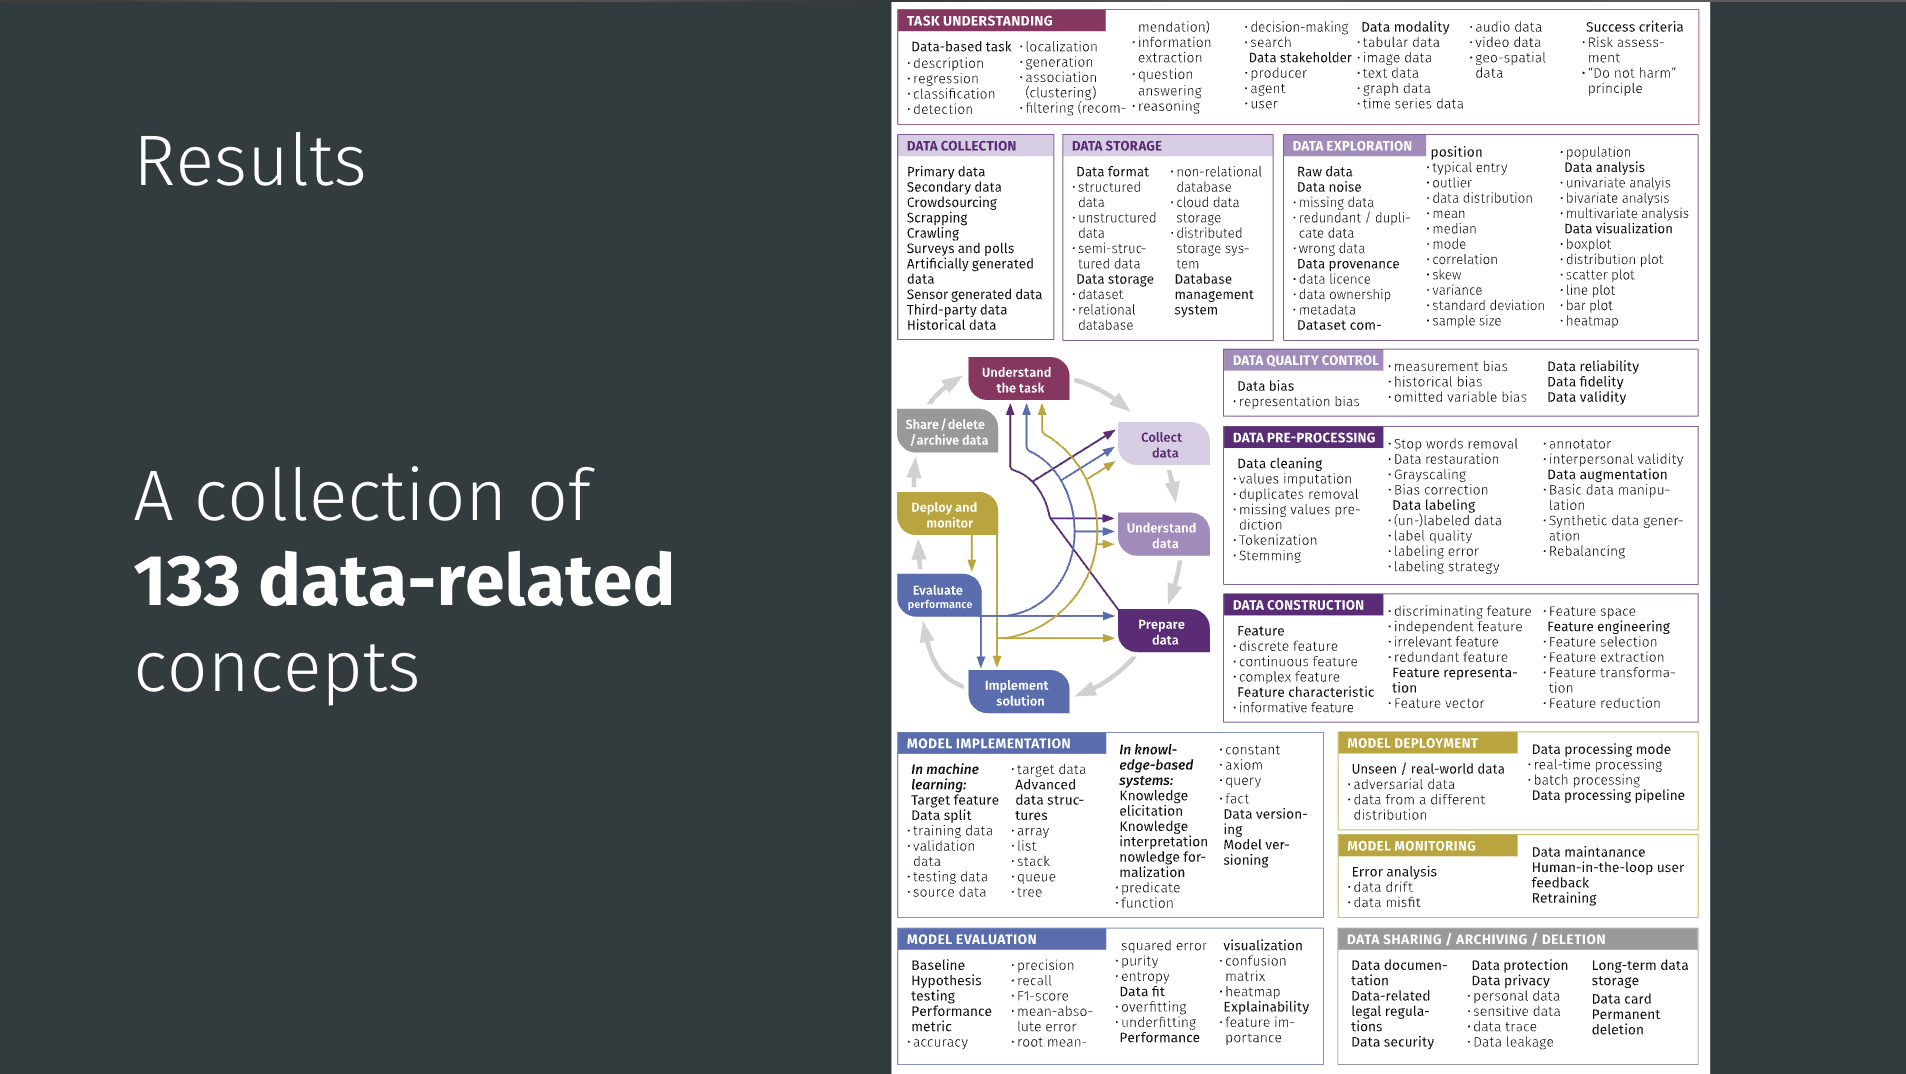
Does AI-assisted coding boost novice programmers’ skills or is it just a shortcut?

Post Syndicated from Isabella Grassl original https://www.raspberrypi.org/blog/does-ai-assisted-coding-boost-novice-programmers-skills-or-is-it-just-a-shortcut/

Artificial intelligence (AI) is transforming industries, and education is no exception. AI-driven development environments (AIDEs), like GitHub Copilot, are opening up new possibilities, and educators and researchers are keen to understand how these tools impact students learning to code. 

In our 50th research seminar, Nicholas Gardella, a PhD candidate at the University of Virginia, shared insights from his research on the effects of AIDEs on beginner programmers’ skills.

Headshot of Nicholas Gardella.
Nicholas Gardella focuses his research on understanding human interactions with artificial intelligence-based code generators to inform responsible adoption in computer science education.

Measuring AI’s impact on students

AI tools are becoming a big part of software development, but what does that mean for students learning to code? As tools like GitHub Copilot become more common, it’s crucial to ask: Do these tools help students to learn better and work more effectively, especially when time is tight?

This is precisely what Nicholas’s research aims to identify by examining the impact of AIDEs on four key areas:

  • Performance (how well students completed the tasks)
  • Workload (the effort required)
  • Emotion (their emotional state during the task)
  • Self-efficacy (their belief in their own abilities to succeed)

Nicholas conducted his study with 17 undergraduate students from an introductory computer science course, who were mostly first-time programmers, with different genders and backgrounds.

Girl in class at IT workshop at university.
By luckybusiness

The students completed programming tasks both with and without the assistance of GitHub Copilot. Nicholas selected the tasks from OpenAI’s human evaluation data set, ensuring they represented a range of difficulty levels. He also used a repeated measures design for the study, meaning that each student had the opportunity to program both independently and with AI assistance multiple times. This design helped him to compare individual progress and attitudes towards using AI in programming.

Less workload, more performance and self-efficacy in learning

The results were promising for those advocating AI’s role in education. Nicholas’s research found that participants who used GitHub Copilot performed better overall, completing tasks with less mental workload and effort compared to solo programming.

Graphic depicting Nicholas' results.
Nicholas used several measures to find out whether AIDEs affected students’ emotional states.

However, the immediate impact on students’ emotional state and self-confidence was less pronounced. Initially, participants did not report feeling more confident while coding with AI. Over time, though, as they became more familiar with the tool, their confidence in their abilities improved slightly. This indicates that students need time and practice to fully integrate AI into their learning process. Students increasingly attributed their progress not to the AI doing the work for them, but to their own growing proficiency in using the tool effectively. This suggests that with sustained practice, students can gain confidence in their abilities to work with AI, rather than becoming overly reliant on it.

Graphic depicting Nicholas' RQ1 results.
Students who used AI tools seemed to improve more quickly than students who worked on the exercises themselves.

A particularly important takeaway from the talk was the reduction in workload when using AI tools. Novice programmers, who often find programming challenging, reported that AI assistance lightened the workload. This reduced effort could create a more relaxed learning environment, where students feel less overwhelmed and more capable of tackling challenging tasks.

However, while workload decreased, use of the AI tool did not significantly boost emotional satisfaction or happiness during the coding process. Nicholas explained that although students worked more efficiently, using the AI tool did not necessarily make coding a more enjoyable experience. This highlights a key challenge for educators: finding ways to make learning both effective and engaging, even when using advanced tools like AI.

AI as a tool for collaboration, not replacement

Nicholas’s findings raise interesting questions about how AI should be introduced in computer science education. While tools like GitHub Copilot can enhance performance, they should not be seen as shortcuts for learning. Students still need guidance in how to use these tools responsibly. Importantly, the study showed that students did not take credit for the AI tool’s work — instead, they felt responsible for their own progress, especially as they improved their interactions with the tool over time.

Seventeen multicoloured post-it notes are roughly positioned in a strip shape on a white board. Each one of them has a hand drawn sketch in pen on them, answering the prompt on one of the post-it notes "AI is...." The sketches are all very different, some are patterns representing data, some are cartoons, some show drawings of things like data centres, or stick figure drawings of the people involved.
Rick Payne and team / Better Images of AI / Ai is… Banner / CC-BY 4.0

Students might become better programmers when they learn how to work alongside AI systems, using them to enhance their problem-solving skills rather than relying on them for answers. This suggests that educators should focus on teaching students how to collaborate with AI, rather than fearing that these tools will undermine the learning process.

Bridging research and classroom realities

Moreover, the study touched on an important point about the limits of its findings. Since the experiment was conducted in a controlled environment with only 17 participants, researchers need to conduct further studies to explore how AI tools perform in real-world classroom settings. For example, the role of internet usage plays a fundamental role. It will be relevant to understand how factors such as class size, prior varying experience, and the age of students affect their ability to integrate AI into their learning.

In the follow-up discussion, Nicholas also demonstrated how AI tools are becoming more accessible within browsers and how teachers can integrate AI-driven development environments more easily into their courses. By making AI technology more readily available, these tools are democratising access to advanced programming aids, enabling students to build applications directly in their web browsers with minimal setup.

The path ahead

Nicholas’s talk provided an insightful look into the evolving relationship between AI tools and novice programmers. While AI can improve performance and reduce workload, it is not a magic solution to all the challenges of learning to code.

Based on the discussion after the talk, educators should support students in developing the skills to use these tools effectively, shaping an environment where they can feel confident working with AI systems. The researchers and educators agreed that more research is needed to expand on these findings, particularly in more diverse and larger-scale educational settings. 

As AI continues to shape the future of programming education, the role of educators will remain crucial in guiding students towards responsible and effective use of these technologies, as we are only at the beginning.

Join our next seminar

In our current seminar series, we are exploring how to teach programming with and without AI technology. Join us at our next seminar on Tuesday, 10 December at 17:00–18:30 GMT to hear Leo Porter (UC San Diego) and Daniel Zingaro (University of Toronto) discuss how they are working to create an introductory programming course for majors and non-majors that fully incorporates generative AI into the learning goals of the course. 

To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.

The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

The post Does AI-assisted coding boost novice programmers’ skills or is it just a shortcut? appeared first on Raspberry Pi Foundation.
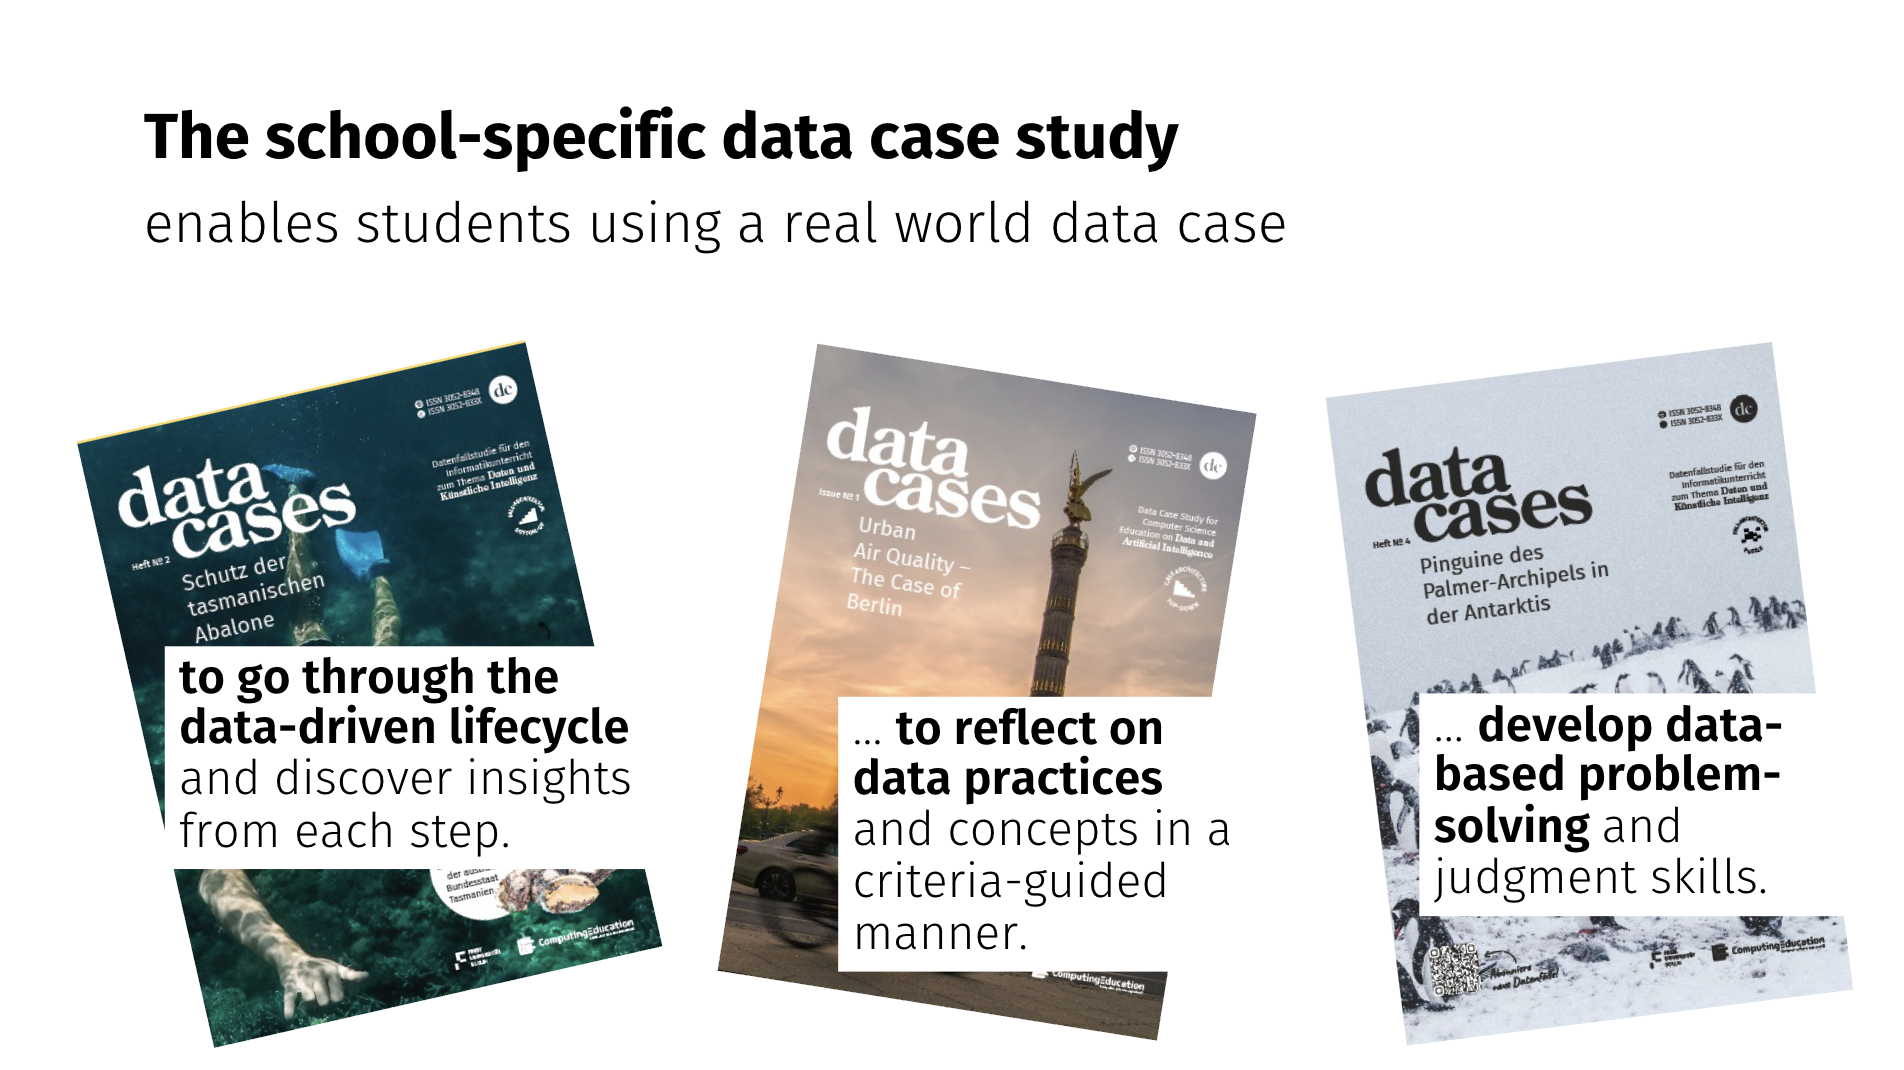
Using generative AI to teach computing: Insights from research

Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/using-generative-ai-to-teach-computing-insights-from-research/

As computing technologies continue to rapidly evolve in today’s digital world, computing education is becoming increasingly essential. Arto Hellas and Juho Leinonen, researchers at Aalto University in Finland, are exploring how innovative teaching methods can equip students with the computing skills they need to stay ahead. In particular, they are looking at how generative AI tools can enhance university-level computing education. 

In our monthly seminar in September, Arto and Juho presented their research on using AI tools to provide personalised learning experiences and automated feedback to help requests, as well as their findings on teaching students how to write effective prompts for generative AI systems. While their research focuses primarily on undergraduate students — given that they teach such students — many of their findings have potential relevance for primary and secondary (K-12) computing education. 

Students attend a lecture at a university.

Generative AI consists of algorithms that can generate new content, such as text, code, and images, based on the input received. Ever since large language models (LLMs) such as ChatGPT and Copilot became widely available, there has been a great deal of attention on how to use this technology in computing education. 

Arto and Juho described generative AI as one of the fastest-moving topics they had ever worked on, and explained that they were trying to see past the hype and find meaningful uses of LLMs in their computing courses. They presented three studies in which they used generative AI tools with students in ways that aimed to improve the learning experience. 

Using generative AI tools to create personalised programming exercises

An important strand of computing education research investigates how to engage students by personalising programming problems based on their interests. The first study in Arto and Juho’s research  took place within an online programming course for adult students. It involved developing a tool that used GPT-4 (the latest version of ChatGPT available at that time) to generate exercises with personalised aspects. Students could select a theme (e.g. sports, music, video games), a topic (e.g. a specific word or name), and a difficulty level for each exercise.

A student in a computing classroom.

Arto, Juho, and their students evaluated the personalised exercises that were generated. Arto and Juho used a rubric to evaluate the quality of the exercises and found that they were clear and had the themes and topics that had been requested. Students’ feedback indicated that they found the personalised exercises engaging and useful, and preferred these over randomly generated exercises. 

Arto and Juho also evaluated the personalisation and found that exercises were often only shallowly personalised, however. In shallow personalisations, the personalised content was added in only one sentence, whereas in deep personalisations, the personalised content was present throughout the whole problem statement. It should be noted that in the examples taken from the seminar below, the terms ‘shallow’ and ‘deep’ were not being used to make a judgement on the worthiness of the topic itself, but were rather describing whether the personalisation was somewhat tokenistic or more meaningful within the exercise. 

In these examples from the study, the shallow personalisation contains only one sentence to contextualise the problem, while in the deep example the whole problem statement is personalised. 

The findings suggest that this personalised approach may be particularly effective on large university courses, where instructors might struggle to give one-on-one attention to every student. The findings further suggest that generative AI tools can be used to personalise educational content and help ensure that students remain engaged. 

How might all this translate to K-12 settings? Learners in primary and secondary schools often have a wide range of prior knowledge, lived experiences, and abilities. Personalised programming tasks could help diverse groups of learners engage with computing, and give educators a deeper understanding of the themes and topics that are interesting for learners. 

Responding to help requests using large language models

Another key aspect of Alto and Juho’s work is exploring how LLMs can be used to generate responses to students’ requests for help. They conducted a study using an online platform containing programming exercises for students. Every time a student struggled with a particular exercise, they could submit a help request, which went into a queue for a teacher to review, comment on, and return to the student. 

The study aimed to investigate whether an LLM could effectively respond to these help requests and reduce the teachers’ workloads. An important principle was that the LLM should guide the student towards the correct answer rather than provide it. 

The study used GPT-3.5, which was the newest version at the time. The results found that the LLM was able to analyse and detect logical and syntactical errors in code, but concerningly, the responses from the LLM also addressed some non-existent problems! This is an example of hallucination, where the LLM outputs something false that does not reflect the real data that was inputted into it. 

An example of how an LLM was able to detect a logical error in code, but also hallucinated and provided an unhelpful, false response about a non-existent syntactical error. 

The finding that LLMs often generated both helpful and unhelpful problem-solving strategies suggests that this is not a technology to rely on in the classroom just yet. Arto and Juho intend to track the effectiveness of LLMs as newer versions are released, and explained that GPT-4 seems to detect errors more accurately, but there is no systematic analysis of this yet. 

In primary and secondary computing classes, young learners often face similar challenges to those encountered by university students — for example, the struggle to write error-free code and debug programs. LLMs seemingly have a lot of potential to support young learners in overcoming such challenges, while also being valuable educational tools for teachers without strong computing backgrounds. Instant feedback is critical for young learners who are still developing their computational thinking skills — LLMs can provide such feedback, and could be especially useful for teachers who may lack the resources to give individualised attention to every learner. Again though, further research into LLM-based feedback systems is needed before they can be implemented en-masse in classroom settings in the future. 

Teaching students how to prompt large language models

    Finally, Arto and Juho presented a study where they introduced the idea of ‘Prompt Problems’: programming exercises where students learn how to write effective prompts for AI code generators using a tool called Promptly. In a Prompt Problem exercise, students are presented with a visual representation of a problem that illustrates how input values will be transformed to an output. Their task is to devise a prompt (input) that will guide an LLM to generate the code (output) required to solve the problem. Prompt-generated code is evaluated automatically by the Promptly tool, helping students to refine the prompt until it produces code that solves the problem.

    The workflow of a Prompt Problem 

    Feedback from students suggested that using Prompt Problems was a good way for them to gain experience of using new programming concepts and develop their computational thinking skills. However, students were frustrated that bugs in the code had to be fixed by amending the prompt — it was not possible to edit the code directly. 

    How these findings relate to K-12 computing education is still to be explored, but they indicate that Prompt Problems with text-based programming languages could be valuable exercises for older pupils with a solid grasp of foundational programming concepts. 

    Balancing the use of AI tools with fostering a sense of community

    At the end of the presentation, Arto and Juho summarised their work and hypothesised that as society develops more and more AI tools, computing classrooms may lose some of their community aspects. They posed a very important question for all attendees to consider: “How can we foster an active community of learners in the generative AI era?” 

    In our breakout groups and the subsequent whole-group discussion, we began to think about the role of community. Some points raised highlighted the importance of working together to accurately identify and define problems, and sharing ideas about which prompts would work best to accurately solve the problems. 

    As AI technology continues to evolve, its role in education will likely expand. There was general agreement in the question and answer session that keeping a sense of community at the heart of computing classrooms will be important. 

    Arto and Juho asked seminar attendees to think about encouraging a sense of community. 

    Further resources

    The Raspberry Pi Computing Education Research Centre and Faculty of Education at the University of Cambridge have recently published a teacher guide on the use of generative AI tools in education. The guide provides practical guidance for educators who are considering using generative AI tools in their teaching. 

    Join our next seminar

    In our current seminar series, we are exploring how to teach programming with and without AI technology. Join us at our next seminar on Tuesday, 12 November at 17:00–18:30 GMT to hear Nicholas Gardella (University of Virginia) discuss the effects of using tools like GitHub Copilot on the motivation, workload, emotion, and self-efficacy of novice programmers. To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.

    The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

    The post Using generative AI to teach computing: Insights from research appeared first on Raspberry Pi Foundation.
    How to make debugging a positive experience for secondary school students

    Post Syndicated from Bonnie Sheppard original https://www.raspberrypi.org/blog/debugging-positive-experience-secondary-school-students/

    Artificial intelligence (AI) continues to change many areas of our lives, with new AI technologies and software having the potential to significantly impact the way programming is taught at schools. In our seminar series this year, we’ve already heard about new AI code generators that can support and motivate young people when learning to code, AI tools that can create personalised Parson’s Problems, and research into how generative AI could improve young people’s understanding of program error messages.

    Two teenage girls do coding activities at their laptops in a classroom.

    At times, it can seem like everything is being automated with AI. However, there are some parts of learning to program that cannot (and probably should not) be automated, such as understanding errors in code and how to fix them. Manually typing code might not be necessary in the future, but it will still be crucial to understand the code that is being generated and how to improve and develop it. 

    As important as debugging might be for the future of programming, it’s still often the task most disliked by novice programmers. Even if program error messages can be explained in the future or tools like LitterBox can flag bugs in an engaging way, actually fixing the issues involves time, effort, and resilience — which can be hard to come by at the end of a computing lesson in the late afternoon with 30 students crammed into an IT room. 

    Debugging can be challenging in many different ways and it is important to understand why students struggle to be able to support them better.

    But what is it about debugging that young people find so hard, even when they’re given enough time to do it? And how can we make debugging a more motivating experience for young people? These are two of the questions that Laurie Gale, a PhD student at the Raspberry Pi Computing Education Research Centre, focused on in our July seminar.

    Why do students find debugging hard?

    Laurie has spent the past two years talking to teachers and students and developing tools (a visualiser of students’ programming behaviour and PRIMMDebug, a teaching process and tool for debugging) to understand why many secondary school students struggle with debugging. It has quickly become clear through his research that most issues are due to problematic debugging strategies and students’ negative experiences and attitudes.

    A photograph of Laurie Gale.
    When Laurie Gale started looking into debugging research for his PhD, he noticed that the majority of studies had been with college students, so he decided to change that and find out what would make debugging easier for novice programmers at secondary school.

    When students first start learning how to program, they have to remember a vast amount of new information, such as different variables, concepts, and program designs. Utilising this knowledge is often challenging because they’re already busy juggling all the content they’ve previously learnt and the challenges of the programming task at hand. When error messages inevitably appear that are confusing or misunderstood, it can become extremely difficult to debug effectively. 

    Program error messages are usually not tailored to the age of the programmers and can be hard to understand and overwhelming for novices.

    Given this information overload, students often don’t develop efficient strategies for debugging. When Laurie analysed the debugging efforts of 12- to 14-year-old secondary school students, he noticed some interesting differences between students who were more and less successful at debugging. While successful students generally seemed to make less frequent and more intentional changes, less successful students tinkered frequently with their broken programs, making one- or two-character edits before running the program again. In addition, the less successful students often ran the program soon after beginning the debugging exercise without allowing enough time to actually read the code and understand what it was meant to do. 

    The issue with these behaviours was that they often resulted in students adding errors when changing the program, which then compounded and made debugging increasingly difficult with each run. 74% of students also resorted to spamming, pressing ‘run’ again and again without changing anything. This strategy resonated with many of our seminar attendees, who reported doing the same thing after becoming frustrated. 

    Educators need to be aware of the negative consequences of students’ exasperating and often overwhelming experiences with debugging, especially if students are less confident in their programming skills to begin with. Even though spending 15 minutes on an exercise shows a remarkable level of tenaciousness and resilience, students’ attitudes to programming — and computing as a whole — can quickly go downhill if their strategies for identifying errors prove ineffective. Debugging becomes a vicious circle: if a student has negative experiences, they are less confident when having to bug-fix again in the future, which can lead to another set of unsuccessful attempts, which can further damage their confidence, and so on. Avoiding this downward spiral is essential. 
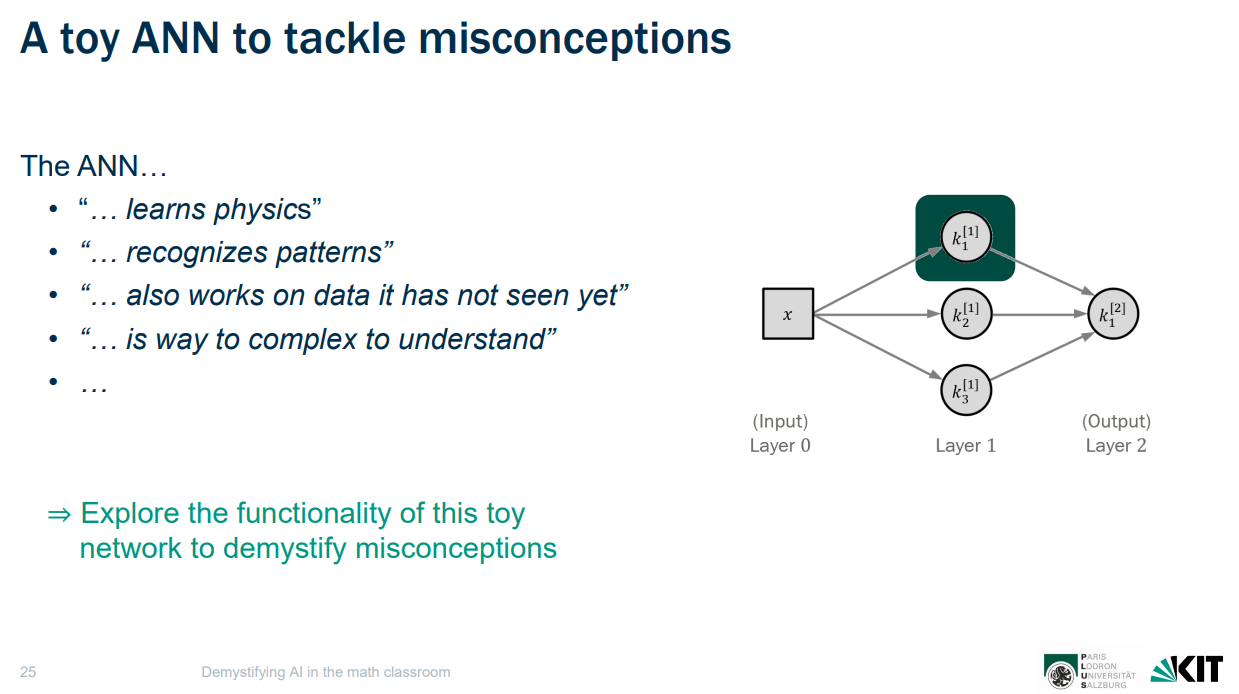
    Approaches to help students engage with debugging

    Laurie stresses the importance of understanding the cognitive challenges of debugging and using the right tools and techniques to empower students and support them in developing effective strategies.
    To make debugging a less cognitively demanding activity, Laurie recommends using a range of tools and strategies in the classroom.

    Some ideas of how to improve debugging skills that were mentioned by Laurie and our attendees included:

    • Using frame-based editing tools for novice programmers because such tools encourage students to focus on logical errors rather than accidental syntax errors, which can distract them from understanding the issues with the program. Teaching debugging should also go hand in hand with understanding programming syntax and using simple language. As one of our attendees put it, “You wouldn’t give novice readers a huge essay and ask them to find errors.”
    • Making error messages more understandable, for example, by explaining them to students using Large Language Models.
    • Teaching systematic debugging processes. There are several different approaches to doing this. One of our participants suggested using the scientific method (forming a hypothesis about what is going wrong, devising an experiment that will provide information to see whether the hypothesis is right, and iterating this process) to methodically understand the program and its bugs. 

    Most importantly, debugging should not be a daunting or stressful experience. Everyone in the seminar agreed that creating a positive error culture is essential. 

    Teachers in Laurie’s study have stressed the importance of positive debugging experiences.

    Some ideas you could explore in your classroom include:

    • Normalising errors: Stress how normal and important program errors are. Everyone encounters them — a professional software developer in our audience said that they spend about half of their time debugging. 
    • Rewarding perseverance: Celebrate the effort, not just the outcome.
    • Modelling how to fix errors: Let your students write buggy programs and attempt to debug them in front of the class.

    In a welcoming classroom where students are given support and encouragement, debugging can be a rewarding experience. What may at first appear to be a failure — even a spectacular one — can be embraced as a valuable opportunity for learning. As a teacher in Laurie’s study said, “If something should have gone right and went badly wrong but somebody found something interesting on the way… you celebrate it. Take the fear out of it.” 

    Watch the recording of Laurie’s presentation:

    Join our next seminar

    In our current seminar series, we are exploring how to teach programming with and without AI.

    Join us at our next seminar on Tuesday, 12 November at 17:00–18:30 GMT to hear Nicholas Gardella (University of Virginia) discuss the effects of using tools like GitHub Copilot on the motivation, workload, emotion, and self-efficacy of novice programmers. To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.

    The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

    The post How to make debugging a positive experience for secondary school students appeared first on Raspberry Pi Foundation.