All posts by Nishchai JM

Improve the discoverability of your unstructured data in Amazon SageMaker Catalog using generative AI

Post Syndicated from Nishchai JM original https://aws.amazon.com/blogs/big-data/improve-the-discoverability-of-your-unstructured-data-in-amazon-sagemaker-catalog-using-generative-ai/

Every day, businesses generate massive amounts of unstructured data such as PDFs, images, emails, customer feedback. Although this data holds valuable business insights, extracting meaningful value from it remains a significant challenge. Its lack of proper context and searchability often keeps it siloed and underutilized, limiting data-driven decision making. Financial reports, legal documents, and customer feedback are prime examples. They contain the answers that your business needs, yet they frequently go unanalyzed due to these barriers.The sheer volume of unstructured content requires scalable infrastructure and automated processing tools, while sensitive information embedded within demands sophisticated classification and protection strategies. Without proper management, organizations face operational inefficiencies, high costs, and increased regulatory risks and reduced AI effectiveness.

What if business context from your PDFs, images, and emails could be automatically extracted and surfaced wherever your teams search for information? In this post, we show you how to implement this. By combining Amazon SageMaker Catalog with generative AI capabilities, you can make unstructured data searchable and queryable through the same interfaces that your teams use for structured data analysis. Success requires balancing advanced AI techniques with governance frameworks so that your data is discoverable and secure for better decision making.

This is a two-part series post. In the first part, we walk you through how to set up the automated processing for unstructured documents, extract and enrich metadata using AI, and make your data discoverable through SageMaker Catalog. The second part is currently in the works and will show you how to discover and access the enriched unstructured data assets as a data consumer. By the end of this post, you will understand how to combine Amazon Textract and Anthropic Claude through Amazon Bedrock to extract key business terms and enrich metadata using Amazon SageMaker Catalog to transform unstructured data into a governed, discoverable asset.

Solutions overviewYou will transform unstructured data into an interactive knowledge base through automated processing within the Amazon SageMaker AI environment. Here is how it works:

  • You will set up an Amazon SageMaker Unified Studio Data Notebook Jupyter-based workspace where you manage your entire processing pipeline, add metadata to unstructured documents like PDFs, photos, emails, or audio recordings stored in Amazon Simple Storage Service (Amazon S3).
  • You will add your files to the SageMaker Project.
  • Amazon Textract extracts information and insights from text, removing manual transcription. This extracted content instantly populates your asset’s README.
  • Amazon Bedrock turns the text into business terms that provide SageMaker Catalog assets the correct business context to help with semantic search or business query search.
  • You will use a publish method to publish the enriched data to the Amazon SageMaker Catalog, making it available to your organization.
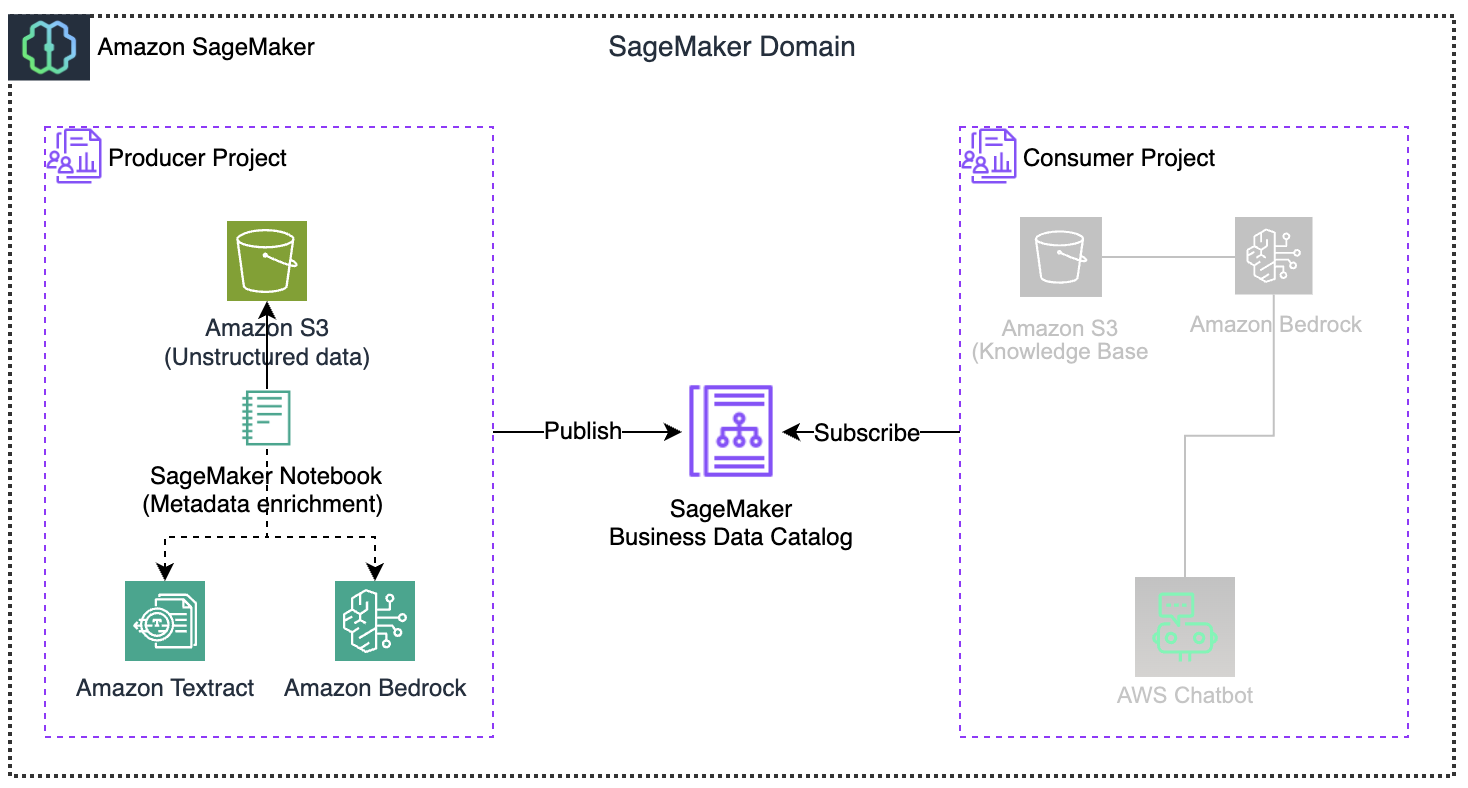
The architecture sets up a pipeline from processing raw documents to enabling end users interaction, with the Amazon SageMaker Catalog serving as the central hub for sending and receiving data. Amazon SageMaker Catalog includes generative AI features that automatically develop and add business descriptions for structured data assets. This capability streamlines documentation processes and provides greater consistency across data assets. You can further enhance this solution to create summaries by also reading and incorporating S3 metadata. This will add more context, such as object properties, access patterns, and storage characteristics, to the extracted document content, streamlining the process to find and catalog data.

Prerequisites

To implement the solution, you must complete the following prerequisites:

  • Create an AWS account – Required to access all AWS services (Amazon SageMaker Catalog, Amazon S3, Amazon Textract, Amazon Bedrock) used in this solution.
  • Create an Amazon SageMaker Unified Studio domain: This provides a collaborative environment for connecting your assets, users, and their projects.
  • Create an SageMaker Project with all capabilities: Your collaborative workspace where you will upload documents, run processing notebooks, and manage permissions for your data enrichment pipeline. Team members added to this project gain immediate access to all shared resources.
    • Producer Project (project name: $(-your-project-name) use “unstructured-producer-project”, project profile: All capabilities)

Solution deployment

Now let’s complete the following steps to deploy and verify the solution.

Prepare source datasets

In this section you will use the following sample datasets by downloading them to your local machine. We will upload these files into your SageMaker Project S3 bucket created in the prerequisite step.

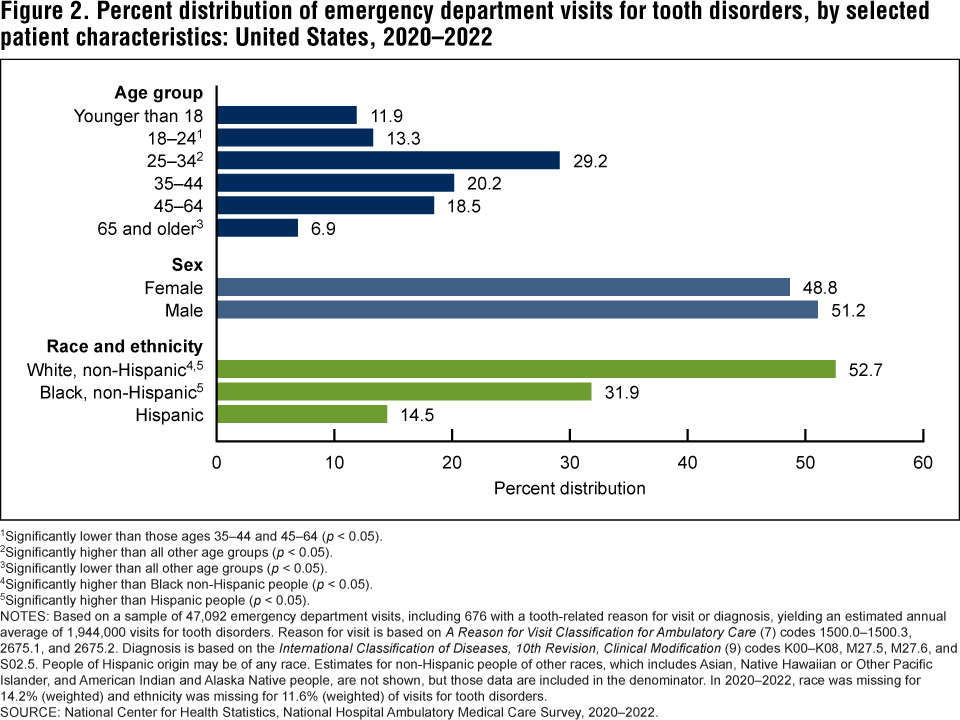
  1. ED_DistributionToothDisorder.png: The dataset shows emergency department visits for tooth disorders in the US from 2020–2022, broken down by age group, gender, and race/ethnicity.
  2. analysisDentalEDvsts.pdf: This report shows emergency department visits analysis for dental conditions across the United States between 2016–2019, showing that among non-traumatic dental visits.
  3.   s3_document_processor_unstructured.ipynb notebook (keep in local environment and will be used at a later stage)

With your sample datasets ready, let’s log in to SageMaker Unified Studio and upload them to your project.

Log in to Amazon SageMaker Unified Studio as a data producer

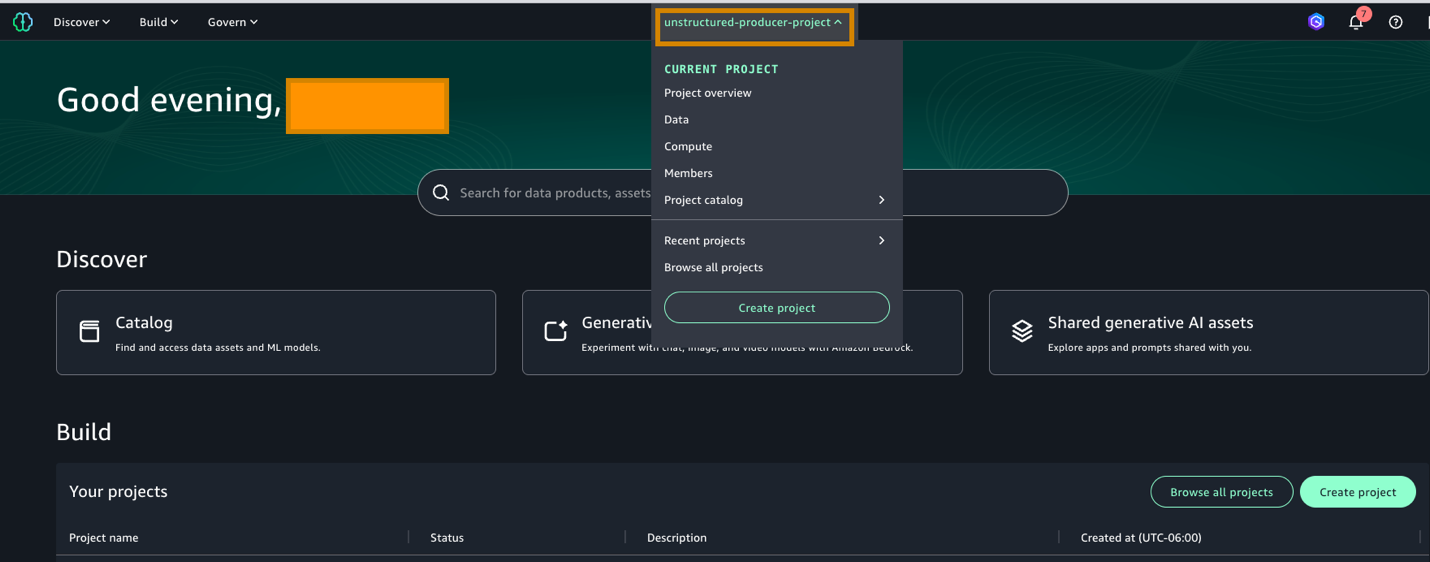
  1. Log in to the SageMaker Unified Studio URL using your username and password. In the portal UI, select the producer project (unstructured-producer-project) that you created in the project selector (at the top center of the screen).
  2. Under Data, do the following:
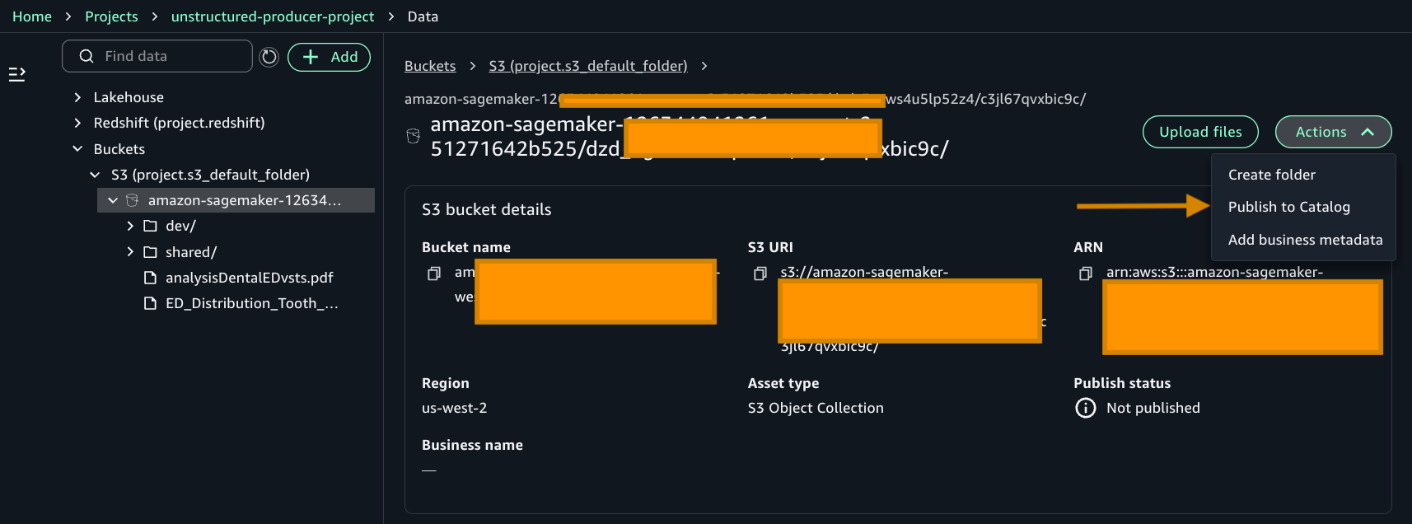
    • Choose the default project bucket created amazon-sagemaker-12*********-us-west-2-51271642b525/dzd_*********/c3jl67qvxbic9c/.
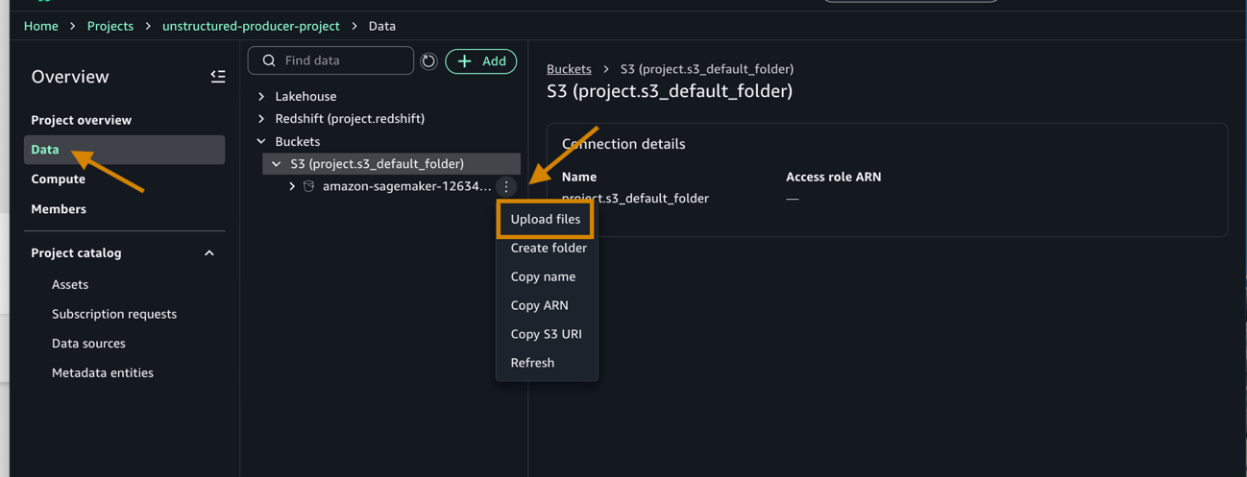
    • Next, choose the three dots and upload the downloaded files (1&2) from the prepared dataset section.
    • After adding the files, choose Publish to Catalog to publish your asset.
Your files are now in the catalog. Before we process them, your project needs permission to access the services. Let’s add those permissions.
  1. Add permissions to an IAM role for the Amazon SageMaker Project role.
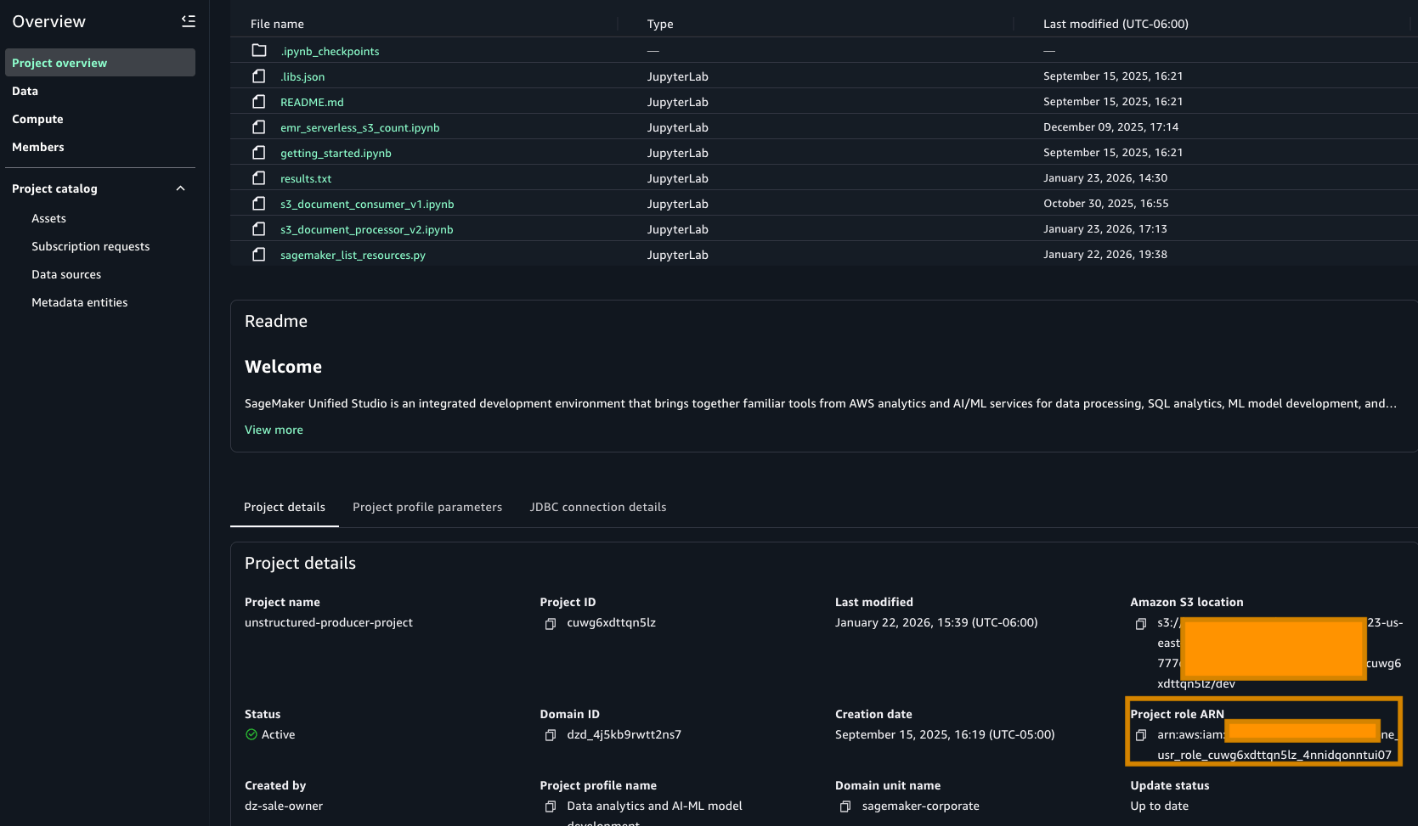
    • Go to the Project overview tab and find the Project role ARN. It can be found in the Project details section.
    • Go to the AWS IAM service and choose Roles. Search for the role as highlighted in the preceding image and add the following permissions. The following policies use full-access managed policies to keep things straightforward for this walkthrough. We don’t recommend this for production environments. Instead, we encourage you to take a moment to review each policy with your security team and scope them down to the least-privilege permissions that your workload needs:
      • Add an AmazonBedrockFullAccess managed policy.
      • Add an AmazonTextractFullAccess managed policy.
      • Add an AmazonS3FullAccess managed policy.
      • Add this inline policy to project policy
        {
            "Version": "2012-10-17",
            "Statement": [
                {
                    "Effect": "Allow",
                    "Action": [
                        "datazone:Search",
                        "datazone:GetAsset",
                        "datazone:CreateAssetRevision",
                        "kms:Decrypt"
                    ],
                    "Resource": "*"
                }
            ]
        }

With permissions configured, let’s set up the governance framework that will classify your documents. We will create glossary terms to tag sensitive and non-sensitive data.

  1. Add Glossary and Glossary terms.
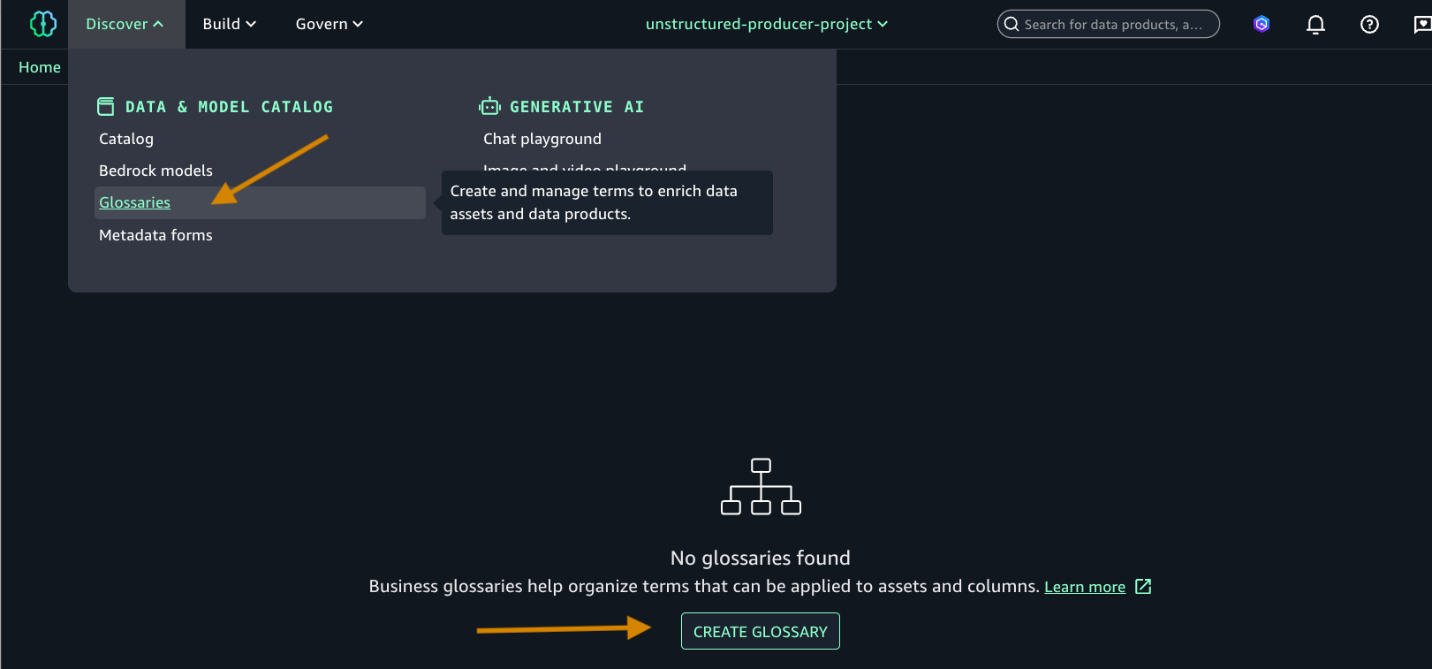
    • Choose Glossaries and CREATE GLOSSARY.
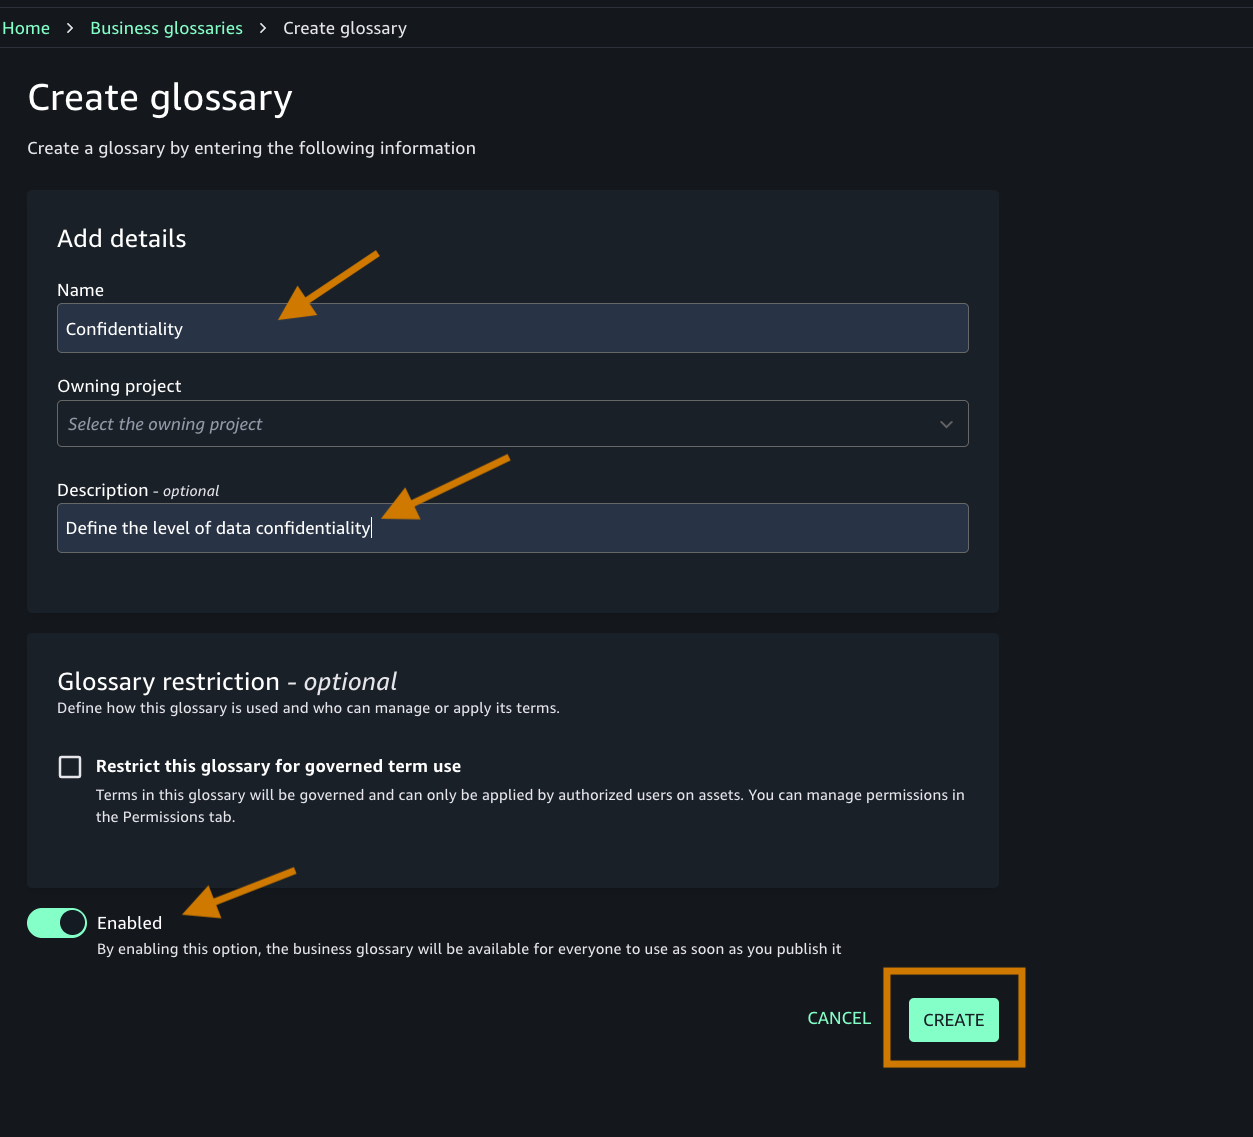
    • Add the following:
    • Name of the glossary and descriptions.
    • Toggle on the Enable button as shown in the following screenshot.
    • Create an appropriate glossary term. You will add this term to your business metadata.
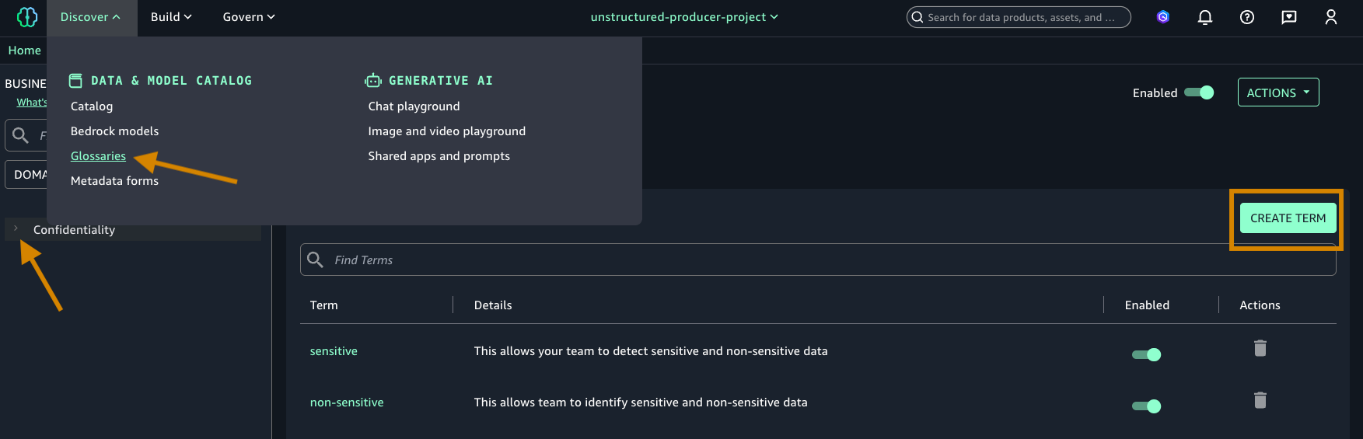
    • Navigate to the Discover menu in the top navigation bar.
    • Choose Glossaries, and then select Create term.
    • Ensure that you’re creating the term under the Confidentiality glossary that you created in step 4.
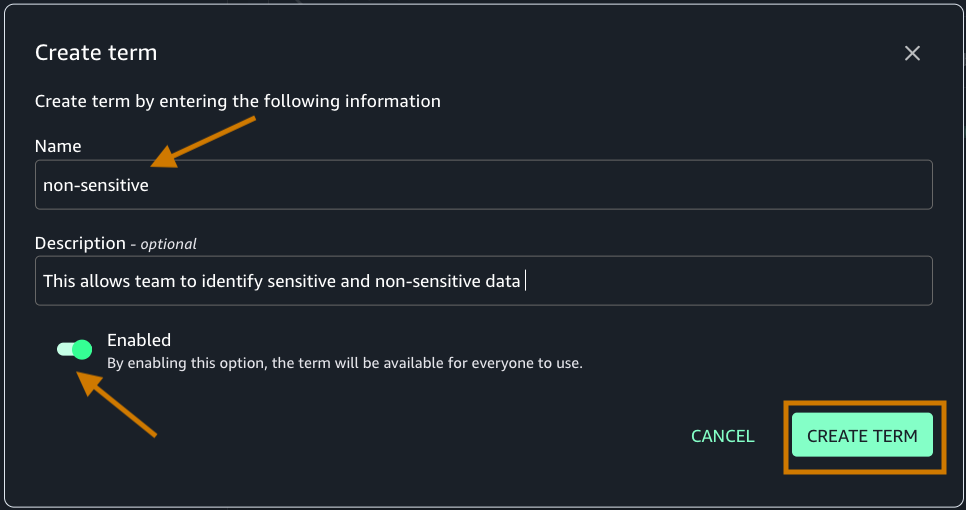
    • Create two terms (sensitive and non-sensitive) and add a description. Make sure that the Enabled toggle is on to enable the new term.

Now that we have configured the necessary permissions and created our glossary terms, let’s proceed with building the business metadata.

Build business metadata

In this section, you will use Amazon Textract and Amazon Bedrock to automatically build and curate business metadata for your assets using a SageMaker Unified Studio Notebook.

  1. From the Project Overview page, access the Compute section in the left menu.
    • Navigate to the Spaces tab.
    • Choose the default space created by your project(default-985-) to begin”.
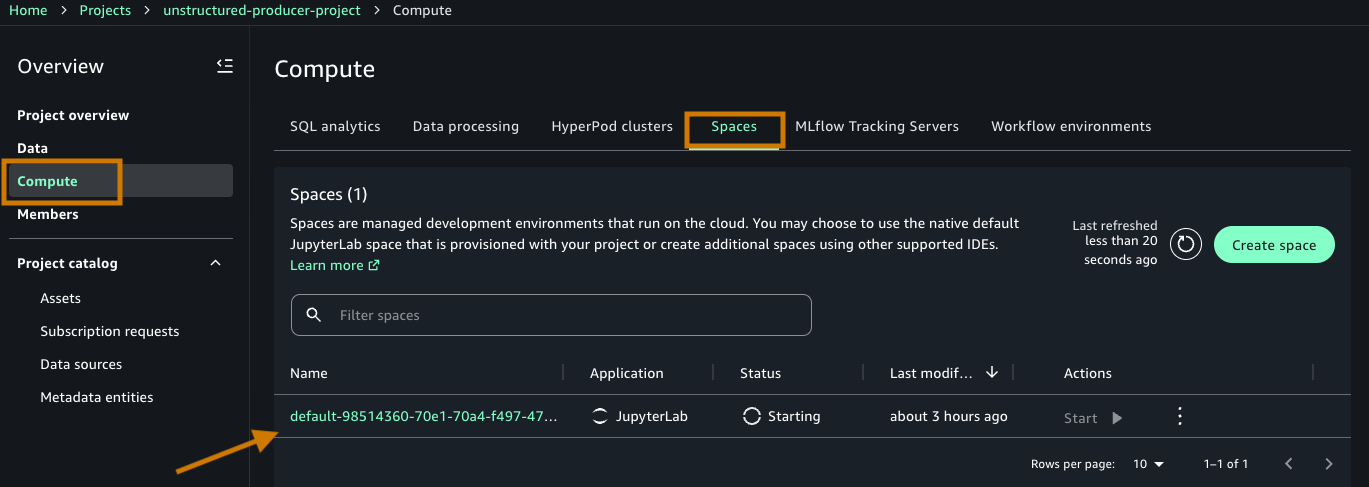
  1. Open the space details page by selecting the Name (default-****).
    • Under Actions, Choose Open space to be taken to the Data Notebook workspace (Jupyter based).
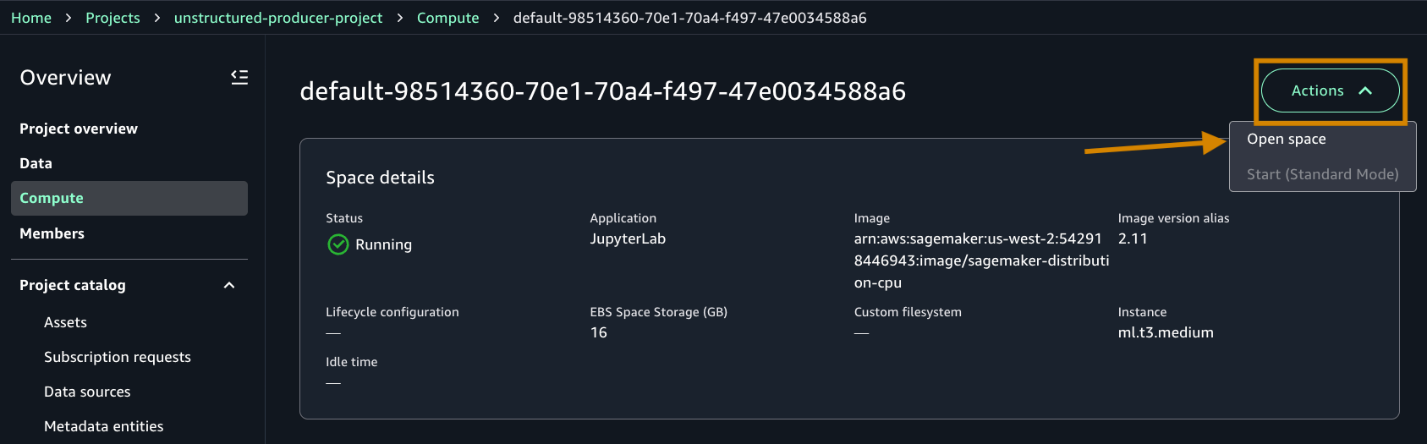
  1. After connected, upload the downloaded notebook from the prerequisite step in your JupyterLab interface by either dragging it into the File browser or using the upload icon.
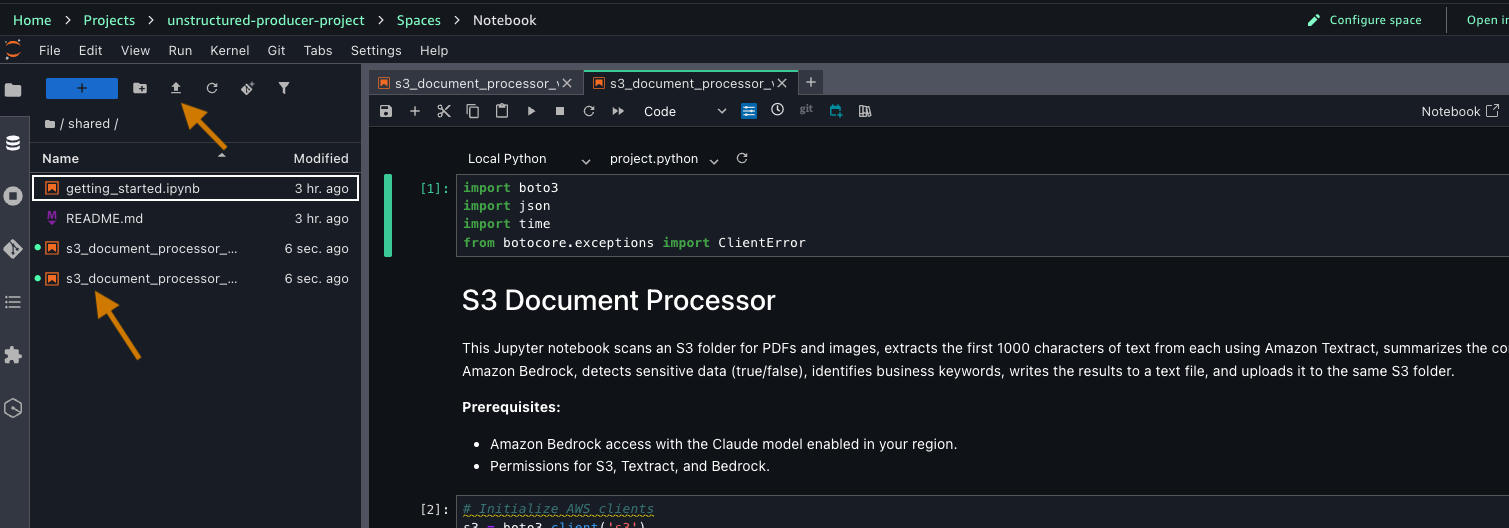
Before running the notebook, let’s understand what each cell does and how they work together to transform your documents into discoverable assets.

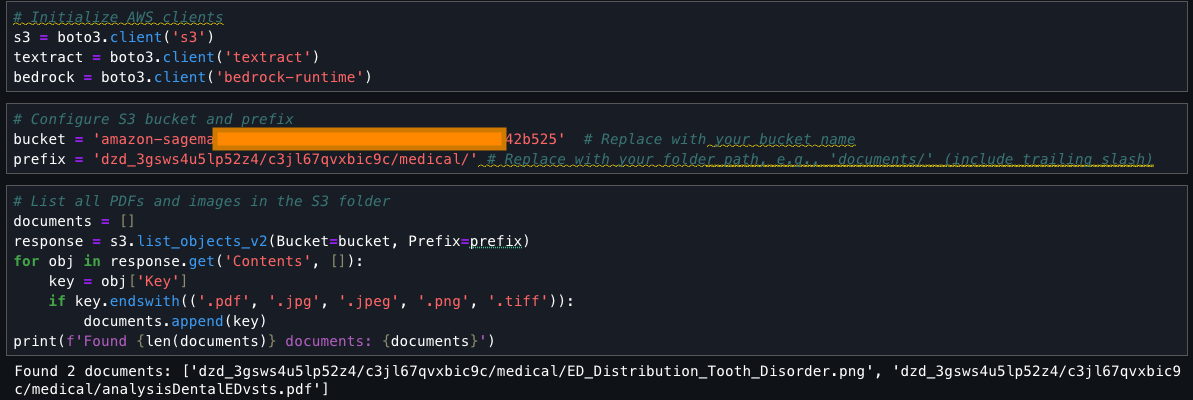
The notebook contains code for processing your documents. It begins by setting up AWS service connections using Boto3, the SDK for Python, importing necessary libraries, and initializing clients for Amazon S3, Amazon Textract, and Amazon Bedrock. The code configures an S3 bucket for processing medical documents.

Now, proceed to run through the individual cells:

This cell searches an S3 bucket for files with specific extensions (.pdf, .jpg, .jpeg, .png, .tiff), collects them into a list called ‘documents’, and prints the total count and names of found files. It uses the list_objects_v2 method to fetch the contents and filters them based on their file extensions.
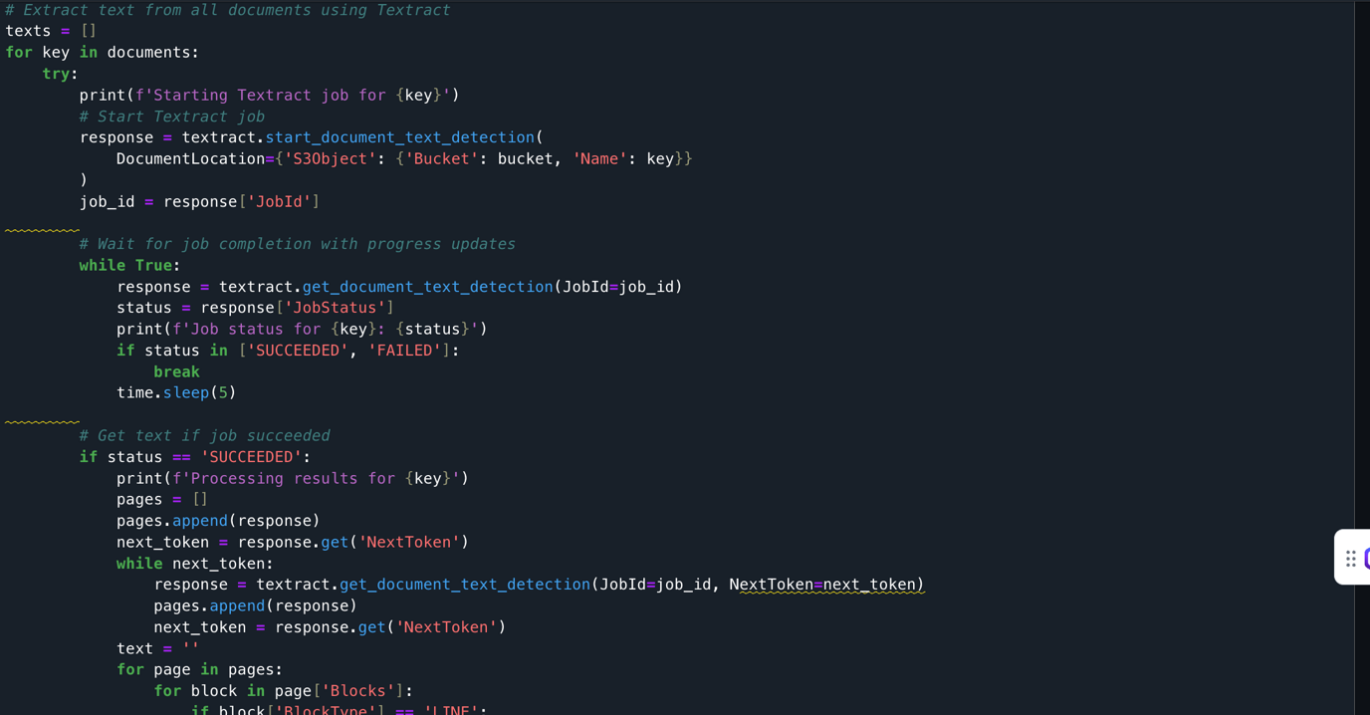
The documents extracted from the S3 bucket are processed using Amazon Textract. It loops through each document, starts an Amazon Textract job, monitors its progress, and when successful, extracts text from all pages. The extracted text is stored in a list along with its document identifier. The code handles pagination, errors, and includes delays between API calls to prevent throttling.
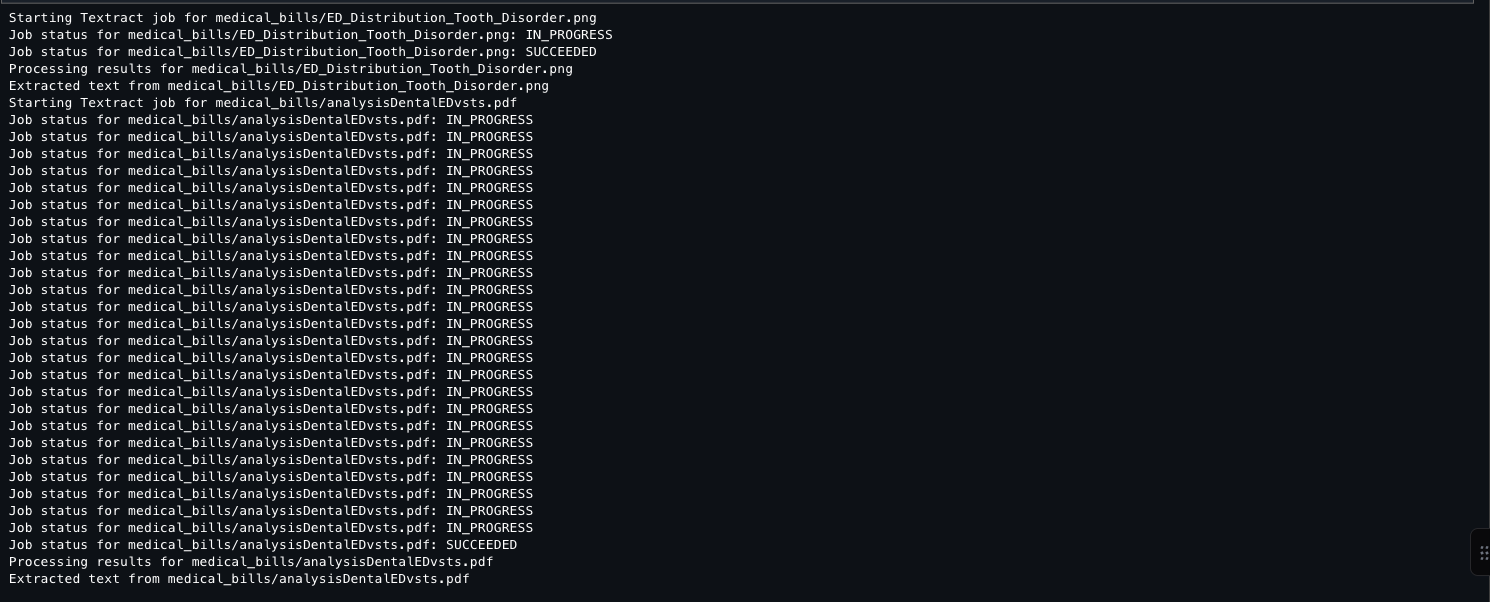
Output [1] The following screenshot shows the output of a Jupyter notebook cell after you run the Amazon Textract API.
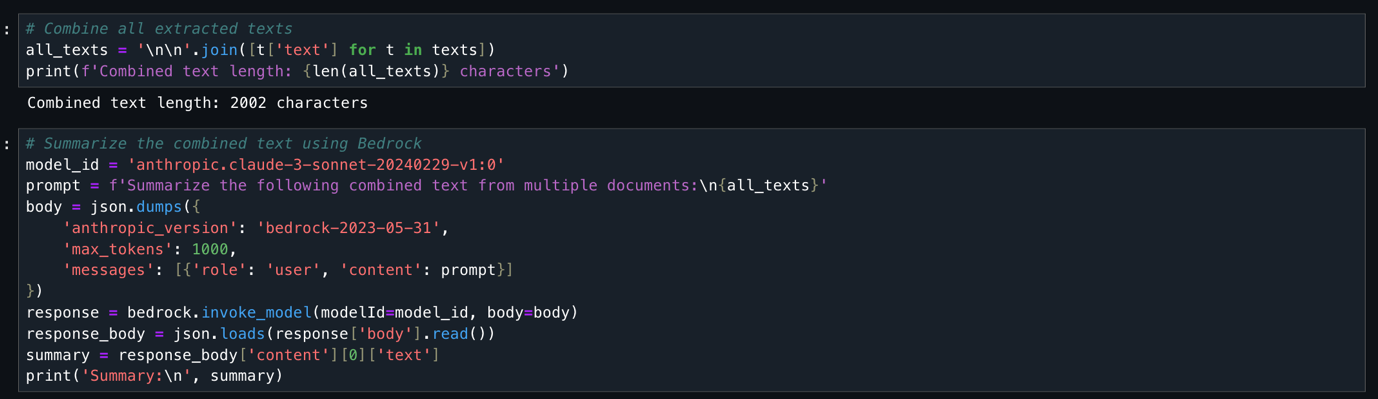
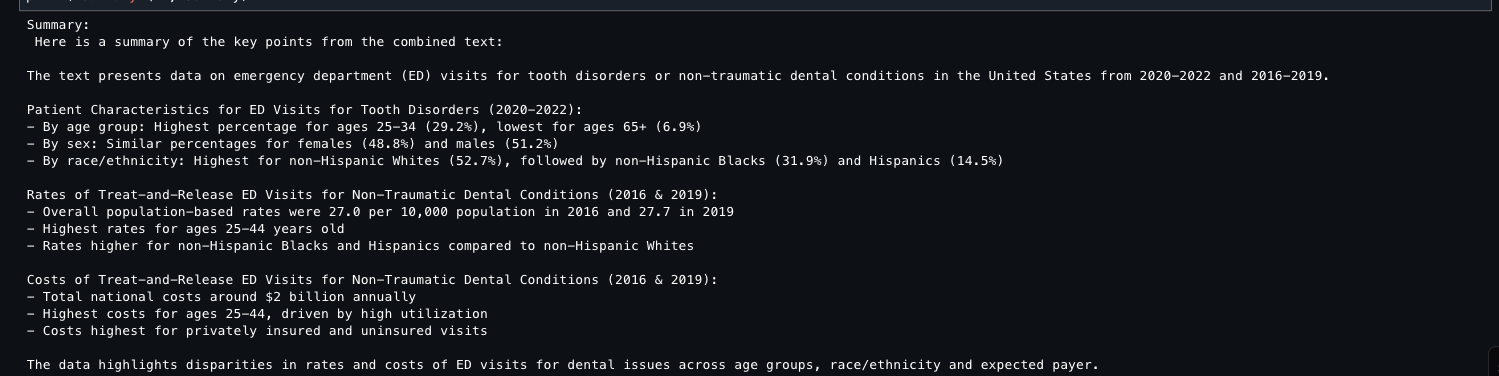
This code takes all previously extracted document text, combines it into one string (2,002 characters total), and uses the Anthropic Claude 3 Sonnet model (available through Amazon Bedrock) to generate a concise summary. The code configures the AI model with specific parameters, sends the combined text for analysis, and returns a summarized version of all document content.
Output [2] The following screenshot shows the proceeding output result.
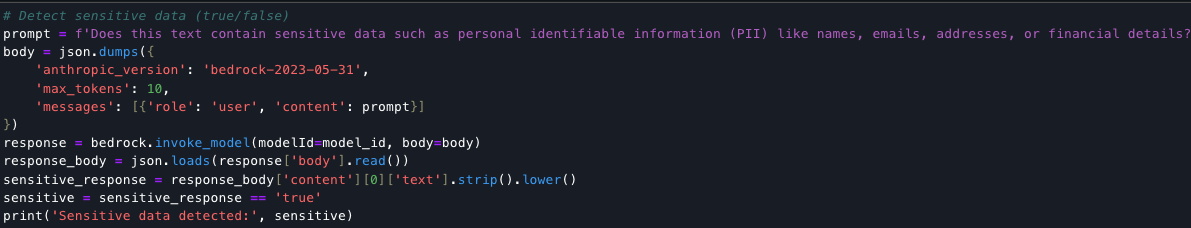
This code detects whether document text contains sensitive PII data (names, emails, addresses, financial details) and returns a Boolean true/false result.
Finally, the code completes the document processing pipeline by classifying the asset based on sensitivity, updating its metadata with an AI-generated summary, and assigning the appropriate glossary term. The script retrieves existing asset details to preserve all metadata forms, updates the README field with the summary content, and creates a new revision. This record of the classification and documentation is stored in the data catalog, accessible alongside your source assets for ongoing governance.
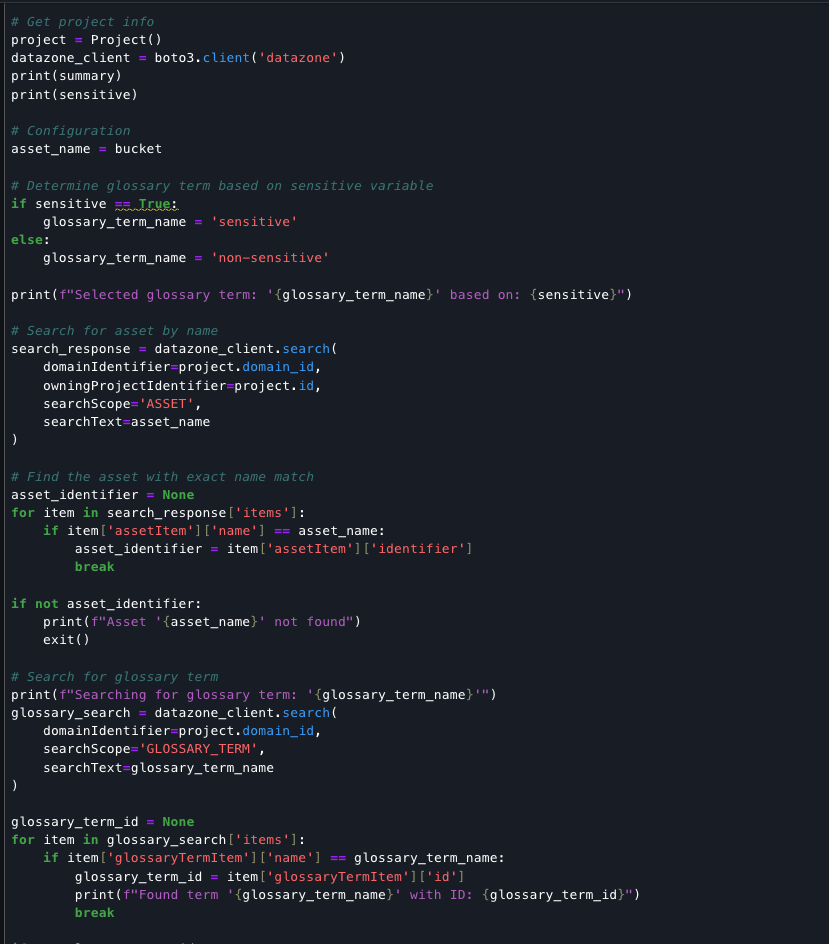
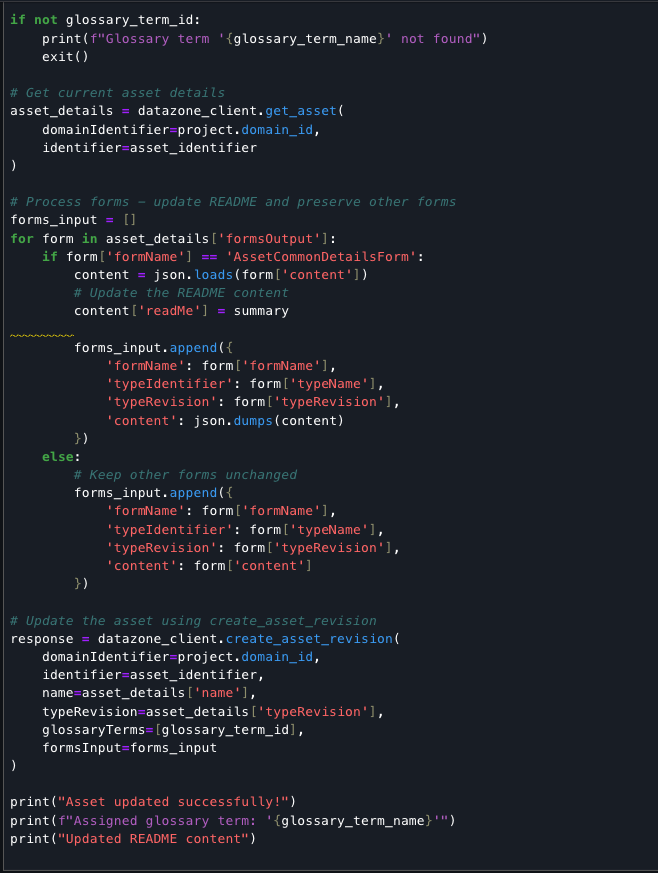
Output: The following screenshot shows the output result.
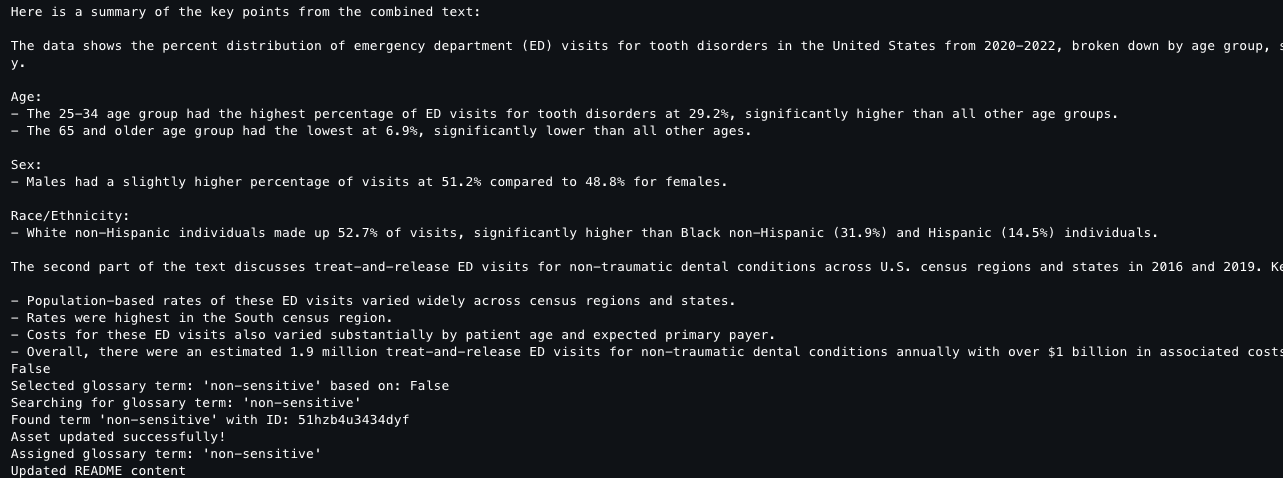
After generating metadata with Amazon Textract and Amazon Bedrock, republish the data to make it discoverable to users. Note the README and the Glossary terms have already been added based on the previous script.

To republish unstructured data with enriched metadata, go to your producer project and choose Re-publish asset.
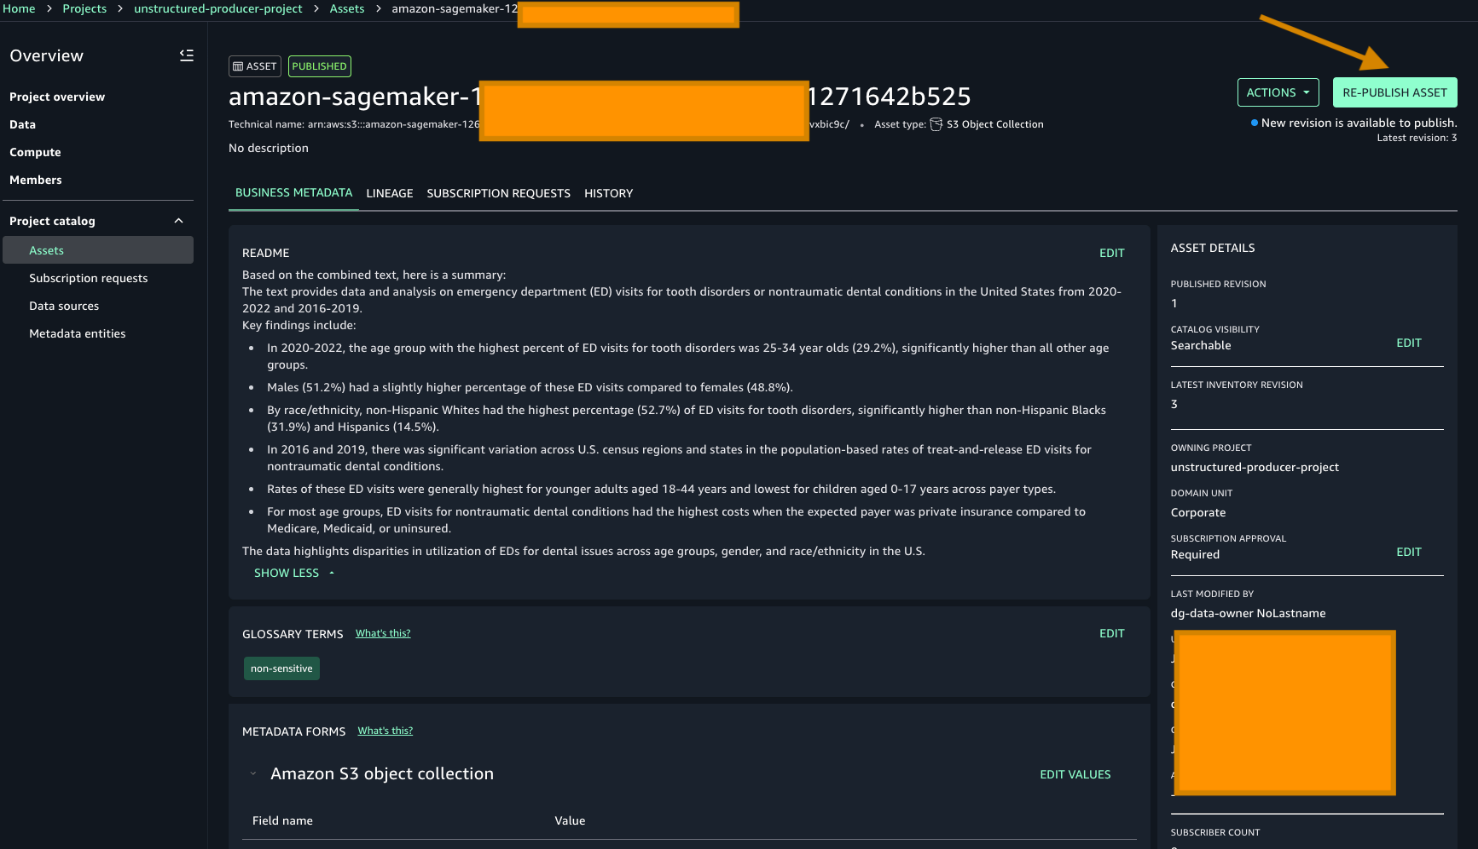
To search for the asset that was published, choose one of the keywords from the README sections. For this example, we search using these keywords high percent of ED visits.

Go to Home in the search bar to enter the keyword. Then choose the asset as displayed in the following screenshot:
As shown in the preceding image, the search results display the asset name along with the project it belongs to. Select the asset to view its details, where you will find rich business metadata, lineage information, and more, as shown in the following screenshot.
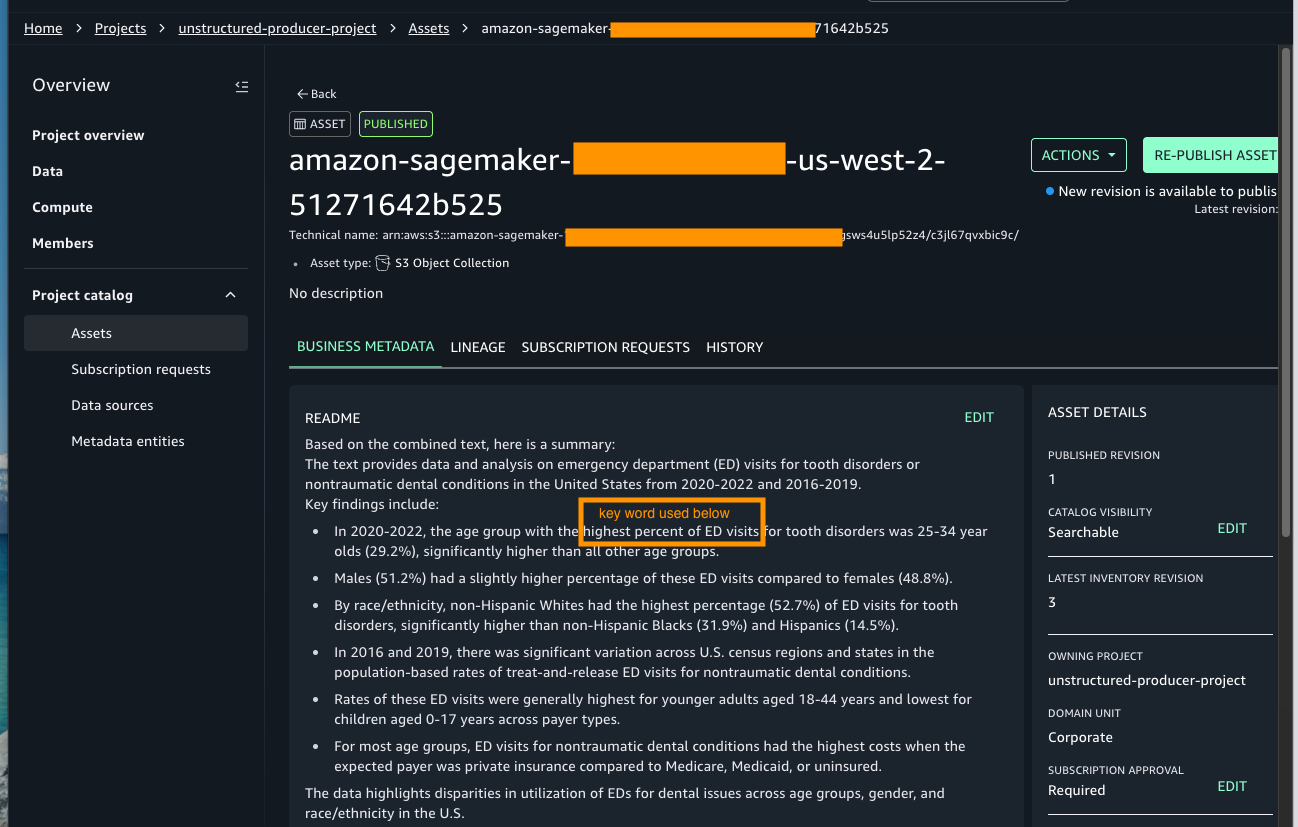
With the asset published and metadata enriched, data assets are ready to be used.

Clean up

To avoid ongoing charges, make sure to delete the resources immediately after completing the tutorial:

  • Stop Studio Resources – Close all running notebooks – Stop any running notebook instances – Shut down unused kernels. Running instances continue to incur charges even when not actively used.
  • Clean S3 Storage – Delete any temporary files created during processing – Remove uploaded test documents if no longer needed. While Amazon S3 costs are minimal, large volumes of unneeded data can accumulate charges.

Conclusion

In this post we showed you how you can transform unstructured data into valuable business assets through seamless integration with AWS services. You can efficiently process documents using Amazon Textract for text extraction, harness the capabilities of Amazon Bedrock for intelligent term identification, and use Amazon SageMaker Catalog for metadata management—all within a secure, governed framework.

Additional resources

To continue your Amazon SageMaker AI journey, see the following resources:


About the authors

Nishchai JM

Nishchai JM

Nishchai is an Analytics and GenAI Specialist Solutions Architect at Amazon Web services. He specializes in building larger scale distributed applications and help customer to modernize their workload on Cloud. He thinks Data is new oil and spends most of his time in deriving insights out of the Data.

KiKi Nwangwu

KiKi Nwangwu

KiKi is a specialist solutions architect at AWS. She specializes in helping customers architect, build, and modernize scalable data analytics and generative AI solutions. She enjoys travelling and exploring new cultures.

Narendra Gupta

Narendra Gupta

Narendra is a Specialist Solutions Architect at AWS, helping customers on their cloud journey with a focus on AWS analytics services. Outside of work, Narendra enjoys learning new technologies, watching movies, and visiting new places.

Ramesh Singh

Ramesh Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon SageMaker team. He is passionate about building high-performance ML/AI and analytics products that help enterprise customers achieve their critical goals using cutting-edge technology.

Harmonize data using AWS Glue and AWS Lake Formation FindMatches ML to build a customer 360 view

Post Syndicated from Nishchai JM original https://aws.amazon.com/blogs/big-data/harmonize-data-using-aws-glue-and-aws-lake-formation-findmatches-ml-to-build-a-customer-360-view/

In today’s digital world, data is generated by a large number of disparate sources and growing at an exponential rate. Companies are faced with the daunting task of ingesting all this data, cleansing it, and using it to provide outstanding customer experience.

Typically, companies ingest data from multiple sources into their data lake to derive valuable insights from the data. These sources are often related but use different naming conventions, which will prolong cleansing, slowing down the data processing and analytics cycle. This problem particularly impacts companies trying to build accurate, unified customer 360 profiles. There are customer records in this data that are semantic duplicates, that is, they represent the same user entity, but have different labels or values. It’s commonly referred to as a data harmonization or deduplication problem. The underlying schemas were implemented independently and don’t adhere to common keys that can be used for joins to deduplicate records using deterministic techniques. This has led to so-called fuzzy deduplication techniques to address the problem. These techniques utilize various machine learning (ML) based approaches.

In this post, we look at how we can use AWS Glue and the AWS Lake Formation ML transform FindMatches to harmonize (deduplicate) customer data coming from different sources to get a complete customer profile to be able to provide better customer experience. We use Amazon Neptune to visualize the customer data before and after the merge and harmonization.

Overview of solution

In this post, we go through the various steps to apply ML-based fuzzy matching to harmonize customer data across two different datasets for auto and property insurance. These datasets are synthetically generated and represent a common problem for entity records stored in multiple, disparate data sources with their own lineage that appear similar and semantically represent the same entity but don’t have matching keys (or keys that work consistently) for deterministic, rule-based matching. The following diagram shows our solution architecture.

We use an AWS Glue job to transform the auto insurance and property insurance customer source data to create a merged dataset containing fields that are common to both datasets (identifiers) that a human expert (data steward) would use to determine semantic matches. The merged dataset is then used to deduplicate customer records using an AWS Glue ML transform to create a harmonized dataset. We use Neptune to visualize the customer data before and after the merge and harmonization to see how the transform FindMacthes can bring all related customer data together to get a complete customer 360 view.

To demonstrate the solution, we use two separate data sources: one for property insurance customers and another for auto insurance customers, as illustrated in the following diagram.

The data is stored in an Amazon Simple Storage Service (Amazon S3) bucket, labeled as Raw Property and Auto Insurance data in the following architecture diagram. The diagram also describes detailed steps to process the raw insurance data into harmonized insurance data to avoid duplicates and build logical relations with related property and auto insurance data for the same customer.

The workflow includes the following steps:

  1. Catalog the raw property and auto insurance data, using an AWS Glue crawler, as tables in the AWS Glue Data Catalog.
  2. Transform raw insurance data into CSV format acceptable to Neptune Bulk Loader, using an AWS Glue extract, transform, and load (ETL) job.
  3. When the data is in CSV format, use an Amazon SageMaker Jupyter notebook to run a PySpark script to load the raw data into Neptune and visualize it in a Jupyter notebook.
  4. Run an AWS Glue ETL job to merge the raw property and auto insurance data into one dataset and catalog the merged dataset. This dataset will have duplicates and no relations are built between the auto and property insurance data.
  5. Create and train an AWS Glue ML transform to harmonize the merged data to remove duplicates and build relations between the related data.
  6. Run the AWS Glue ML transform job. The job also catalogs the harmonized data in the Data Catalog and transforms the harmonized insurance data into CSV format acceptable to Neptune Bulk Loader.
  7. When the data is in CSV format, use a Jupyter notebook to run a PySpark script to load the harmonized data into Neptune and visualize it in a Jupyter notebook.

Prerequisites

To follow along with this walkthrough, you must have an AWS account. Your account should have permission to provision and run an AWS CloudFormation script to deploy the AWS services mentioned in the architecture diagram of the solution.

Provision required resources using AWS CloudFormation:

To launch the CloudFormation stack that configures the required resources for this solution in your AWS account, complete the following steps:

  1. Log in to your AWS account and choose Launch Stack:

  1. Follow the prompts on the AWS CloudFormation console to create the stack.
  2. When the launch is complete, navigate to the Outputs tab of the launched stack and note all the key-value pairs of the resources provisioned by the stack.

Verify the raw data and script files S3 bucket

On the CloudFormation stack’s Outputs tab, choose the value for S3BucketName. The S3 bucket name should be cloud360-s3bucketstack-xxxxxxxxxxxxxxxxxxxxxxxx and should contain folders similar to the following screenshot.

The following are some important folders:

  • auto_property_inputs – Contains raw auto and property data
  • merged_auto_property – Contains the merged data for auto and property insurance
  • output – Contains the delimited files (separate subdirectories)

Catalog the raw data

To help walk through the solution, the CloudFormation stack created and ran an AWS Glue crawler to catalog the property and auto insurance data. To learn more about creating and running AWS Glue crawlers, refer to Working with crawlers on the AWS Glue console. You should see the following tables created by the crawler in the c360_workshop_db AWS Glue database:

  • source_auto_address – Contains address data of customers with auto insurance
  • source_auto_customer – Contains auto insurance details of customers
  • source_auto_vehicles – Contains vehicle details of customers
  • source_property_addresses – Contains address data of customers with property insurance
  • source_property_customers – Contains property insurance details of customers

You can review the data using Amazon Athena. For more information about using Athena to query an AWS Glue table, refer to Running SQL queries using Amazon Athena. For example, you can run the following SQL query:

SELECT * FROM "c360_workshop_db"."source_auto_address" limit 10;

Convert the raw data into CSV files for Neptune

The CloudFormation stack created and ran the AWS Glue ETL job prep_neptune_data to convert the raw data into CSV format acceptable to Neptune Bulk Loader. To learn more about building an AWS Glue ETL job using AWS Glue Studio and to review the job created for this solution, refer to Creating ETL jobs with AWS Glue Studio.

Verify the completion of job run by navigating to the Runs tab and checking the status of most recent run.

Verify the CSV files created by the AWS Glue job in the S3 bucket under the output folder.

Load and visualize the raw data in Neptune

This section uses SageMaker Jupyter notebooks to load, query, explore, and visualize the raw property and auto insurance data in Neptune. Jupyter notebooks are web-based interactive platforms. We use Python scripts to analyze the data in a Jupyter notebook. A Jupyter notebook with the required Python scripts has already been provisioned by the CloudFormation stack.

  1. Start Jupyter Notebook.
  2. Choose the Neptune folder on the Files tab.

  1. Under the Customer360 folder, open the notebook explore_raw_insurance_data.ipynb.

  1. Run Steps 1–5 in the notebook to analyze and visualize the raw insurance data.

The rest of the instructions are inside the notebook itself. The following is a summary of the tasks for each step in the notebook:

  • Step 1: Retrieve Config – Run this cell to run the commands to connect to Neptune for Bulk Loader.
  • Step 2: Load Source Auto Data – Load the auto insurance data into Neptune as vertices and edges.
  • Step 3: Load Source Property Data – Load the property insurance data into Neptune as vertices and edges.
  • Step 4: UI Configuration – This block sets up the UI config and provides UI hints.
  • Step 5: Explore entire graph – The first block builds and displays a graph for all customers with more than four coverages of auto or property insurance policies. The second block displays the graph for four different records for a customer with the name James.

These are all records for the same customer, but because they’re not linked in any way, they appear as different customer records. The AWS Glue FindMatches ML transform job will identify these records as customer James, and the records provide complete visibility on all policies owned by James. The Neptune graph looks like the following example. The vertex covers represents the coverage of auto or property insurance by the owner (James in this case) and the vertex locatedAt represents the address of the property or vehicle that is covered by the owner’s insurance.

Merge the raw data and crawl the merged dataset

The CloudFormation stack created and ran the AWS Glue ETL job merge_auto_property to merge the raw property and auto insurance data into one dataset and catalog the resultant dataset in the Data Catalog. The AWS Glue ETL job does the following transforms on the raw data and merges the transformed data into one dataset:

  • Changes the following fields on the source table source_auto_customer:
    1. Changes policyid to id and data type to string
    2. Changes fname to first_name
    3. Changes lname to last_name
    4. Changes work to company
    5. Changes dob to date_of_birth
    6. Changes phone to home_phone
    7. Drops the fields birthdate, priority, policysince, and createddate
  • Changes the following fields on the source_property_customers:
    1. Changes customer_id to id and data type to string
    2. Changes social to ssn
    3. Drops the fields job, email, industry, city, state, zipcode, netnew, sales_rounded, sales_decimal, priority, and industry2
  • After converting the unique ID field in each table to string type and renaming it to id, the AWS Glue job appends the suffix -auto to all id fields in the source_auto_customer table and the suffix -property to all id fields in the source_propery_customer table before copying all the data from both tables into the merged_auto_property table.

Verify the new table created by the job in the Data Catalog and review the merged dataset using Athena using below Athena SQL query:

SELECT * FROM "c360_workshop_db"."merged_auto_property" limit 10

For more information about how to review the data in the merged_auto_property table, refer to Running SQL queries using Amazon Athena.

Create, teach, and tune the Lake Formation ML transform

The merged AWS Glue job created a Data Catalog called merged_auto_property. Preview the table in Athena Query Editor and download the dataset as a CSV from the Athena console. You can open the CSV file for quick comparison of duplicates.

The rows with IDs 11376-property and 11377-property are mostly same except for the last two digits of their SSN, but these are mostly human errors. The fuzzy matches are easy to spot by a human expert or data steward with domain knowledge of how this data was generated, cleansed, and processed in the various source systems. Although a human expert can identify those duplicates on a small dataset, it becomes tedious when dealing with thousands of records. The AWS Glue ML transform builds on this intuition and provides an easy-to-use ML-based algorithm to automatically apply this approach to large datasets efficiently.

Create the FindMatches ML transform

  1. On the AWS Glue console, expand Data Integration and ETL in the navigation pane.
  2. Under Data classification tools, choose Record Matching.

This will open the ML transforms page.

  1. Choose Create transform.
  2. For Name, enter c360-ml-transform.
  3. For Existing IAM role, choose GlueServiceRoleLab.
  4. For Worker type, choose G.2X (Recommended).
  5. For Number of workers, enter 10.
  6. For Glue version, choose as Spark 2.4 (Glue Version 2.0).
  7. Keep the other values as default and choose Next.

  1. For Database, choose c360_workshop_db.
  2. For Table, choose merged_auto_property.
  3. For Primary key, select id.
  4. Choose Next.

  1. In the Choose tuning options section, you can tune performance and cost metrics available for the ML transform. We stay with the default trade-offs for a balanced approach.

We have specified these values to achieve balanced results. If needed, you can adjust these values later by selecting the transform and using the Tune menu.

  1. Review the values and choose Create ML transform.

The ML transform is now created with the status Needs training.

Teach the transform to identify the duplicates

In this step, we teach the transform by providing labeled examples of matching and non-matching records. You can create your labeling set yourself or allow AWS Glue to generate the labeling set based on heuristics. AWS Glue extracts records from your source data and suggests potential matching records. The file will contain approximately 100 data samples for you to work with.

  1. On the AWS Glue console, navigate to the ML transforms page.
  2. Select the transform c360-ml-transform and choose Train model.

  1. Select I have labels and choose Browse S3 to upload labels from Amazon S3.


Two labeled files have been created for this example. We upload these files to teach the ML transform.

  1. Navigate to the folder label in your S3 bucket, select the labeled file (Label-1-iteration.csv), and choose Choose. And Click “Upload labeling file from S3”.
  2. A green banner appears for successful uploads.
  3. Upload another label file (Label-2-iteration.csv) and select Append to my existing labels.
  4. Wait for the successful upload, then choose Next.

  1. Review the details in the Estimate quality metrics section and choose Close.

Verify that the ML transform status is Ready for use. Note that the label count is 200 because we successfully uploaded two labeled files to teach the transform. Now we can use it in an AWS Glue ETL job for fuzzy matching of the full dataset.

Before proceeding to the next steps, note the transform ID (tfm-xxxxxxx) for the created ML transform.

Harmonize the data, catalog the harmonized data, and convert the data into CSV files for Neptune

In this step, we run an AWS Glue ML transform job to find matches in the merged data. The job also catalogs the harmonized dataset in the Data Catalog and converts the merged [A1] dataset into CSV files for Neptune to show the relations in the matched records.

  1. On the AWS Glue console, choose Jobs in the navigation pane.
  2. Choose the job perform_ml_dedup.

  1. On the job details page, expand Additional properties.
  2. Under Job parameters, enter the transform ID you saved earlier and save the settings.

    1. Choose Run and monitor the job status for completion.

  1. Run the following query in Athena to review the data in the new table ml_matched_auto_property, created and cataloged by the AWS Glue job, and observe the results:
SELECT * FROM c360_workshop_db.ml_matched_auto_property WHERE first_name like 'Jam%' and last_name like 'Sanchez%';

The job has added a new column called match_id. If multiple records follow the match criteria, then all matching records have the same match_id.

Match IDs play a crucial role in data harmonization using Lake Formation FindMatches. Each row is assigned a unique integer match ID based on matching criteria such as first_name, last_name, SSN, or date_of_birth, as defined in the uploaded label file. For instance, match ID 25769803941 is assigned to all records that meet the match criteria, such as row 1, 2, 4, and 5 which share the same last_name, SSN, and date_of_birth. Consequently, the properties with ID 19801-property, 29801-auto, 19800-property, and 29800-auto all share the same match ID. It’s important to take note of the match ID because it will be utilized for Neptune Gremlin queries.

The output of the AWS Glue job also has created two files, master_vertex.csv and master_edge.csv, in the S3 bucket output/master_data. We use these files to load data into the Neptune database to find the relationship among different entities.

Load and visualize the harmonized data in Neptune

This section uses Jupyter notebooks to load, query, explore, and visualize the ML matched auto and property insurance data in Neptune. Complete the following steps:

  1. Start Jupyter Notebook.
  2. Choose the Neptune folder on the Files tab.
  3. Under the Customer360 folder, choose the notebook. explore_harmonized_insurance_data.ipynb.
  4. Run Steps 1–5 in the notebook to analyze and visualize the raw insurance data.

The rest of the instructions are inside the notebook itself. The following is a summary of the tasks for each step in the notebook:

  • Step 1. Retrieve Config – Run this cell to run the commands to connect to Neptune for Bulk Loader.
  • Step 2. Load Harmonized Customer Data – Load the final vertex and edge files into Neptune.
  • Step 3. Initialize Neptune node traversals – This block sets up the UI config and provides UI hints.
  • Step 4. Exploring Customer 360 graph – Replace the Match_id 25769803941 copied from the previous step into g.V('REPLACE_ME')( If its not replaced already ) and run the cell.

This displays the graph for four different records for a customer with first_name, and James and JamE are is now connected with the SameAs vertex. The Neptune graph helps connect different entities with match criteria; the AWS Glue FindMatches ML transform job has identified these records as customer James and the records show the Match_id is the same for them. The following diagram shows an example of the Neptune graph. The vertex covers represents the coverage of auto or property insurance by the owner (James in this case) and the vertex locatedAt represents the address of the property or vehicle that is covered by the owner’s insurance.

Clean up

To avoid incurring additional charges to your account, on the AWS CloudFormation console, select the stack that you provisioned as part of this post and delete it.

Conclusion

In this post, we showed how to use the AWS Lake Formation FindMatch transform for fuzzy matching data on a data lake to link records if there are no join keys and group records with similar match IDs. You can use Amazon Neptune to establish the relationship between records and visualize the connect graph for deriving insights.

We encourage you to explore our range of services and see how they can help you achieve your goals. For more data and analytics blog posts, check out AWS Blogs.


About the Authors

Nishchai JM is an Analytics Specialist Solutions Architect at Amazon Web services. He specializes in building Big-data applications and help customer to modernize their applications on Cloud. He thinks Data is new oil and spends most of his time in deriving insights out of the Data.

Varad Ram is Senior Solutions Architect in Amazon Web Services. He likes to help customers adopt to cloud technologies and is particularly interested in artificial intelligence. He believes deep learning will power future technology growth. In his spare time, he like to be outdoor with his daughter and son.
Narendra Gupta is a Specialist Solutions Architect at AWS, helping customers on their cloud journey with a focus on AWS analytics services. Outside of work, Narendra enjoys learning new technologies, watching movies, and visiting new places

Arun A K is a Big Data Solutions Architect with AWS. He works with customers to provide architectural guidance for running analytics solutions on the cloud. In his free time, Arun loves to enjoy quality time with his family

Optimize Federated Query Performance using EXPLAIN and EXPLAIN ANALYZE in Amazon Athena

Post Syndicated from Nishchai JM original https://aws.amazon.com/blogs/big-data/optimize-federated-query-performance-using-explain-and-explain-analyze-in-amazon-athena/

Amazon Athena is an interactive query service that makes it easy to analyze data in Amazon Simple Storage Service (Amazon S3) using standard SQL. Athena is serverless, so there is no infrastructure to manage, and you pay only for the queries that you run. In 2019, Athena added support for federated queries to run SQL queries across data stored in relational, non-relational, object, and custom data sources.

In 2021, Athena added support for the EXPLAIN statement, which can help you understand and improve the efficiency of your queries. The EXPLAIN statement provides a detailed breakdown of a query’s run plan. You can analyze the plan to identify and reduce query complexity and improve its runtime. You can also use EXPLAIN to validate SQL syntax prior to running the query. Doing so helps prevent errors that would have occurred while running the query.

Athena also added EXPLAIN ANALYZE, which displays the computational cost of your queries alongside their run plans. Administrators can benefit from using EXPLAIN ANALYZE because it provides a scanned data count, which helps you reduce financial impact due to user queries and apply optimizations for better cost control.

In this post, we demonstrate how to use and interpret EXPLAIN and EXPLAIN ANALYZE statements to improve Athena query performance when querying multiple data sources.

Solution overview

To demonstrate using EXPLAIN and EXPLAIN ANALYZE statements, we use the following services and resources:

Athena uses the AWS Glue Data Catalog to store and retrieve table metadata for the Amazon S3 data in your AWS account. The table metadata lets the Athena query engine know how to find, read, and process the data that you want to query. We use Athena data source connectors to connect to data sources external to Amazon S3.

Prerequisites

To deploy the CloudFormation template, you must have the following:

Provision resources with AWS CloudFormation

To deploy the CloudFormation template, complete the following steps:

  1. Choose Launch Stack:

  1. Follow the prompts on the AWS CloudFormation console to create the stack.
  2. Note the key-value pairs on the stack’s Outputs tab.

You use these values when configuring the Athena data source connectors.

The CloudFormation template creates the following resources:

  • S3 buckets to store data and act as temporary spill buckets for Lambda
  • AWS Glue Data Catalog tables for the data in the S3 buckets
  • A DynamoDB table and Amazon RDS for MySQL tables, which are used to join multiple tables from different sources
  • A VPC, subnets, and endpoints, which are needed for Amazon RDS for MySQL and DynamoDB

The following figure shows the high-level data model for the data load.

Create the DynamoDB data source connector

To create the DynamoDB connector for Athena, complete the following steps:

  1. On the Athena console, choose Data sources in the navigation pane.
  2. Choose Create data source.
  3. For Data sources, select Amazon DynamoDB.
  4. Choose Next.

  1. For Data source name, enter DDB.

  1. For Lambda function, choose Create Lambda function.

This opens a new tab in your browser.

  1. For Application name, enter AthenaDynamoDBConnector.
  2. For SpillBucket, enter the value from the CloudFormation stack for AthenaSpillBucket.
  3. For AthenaCatalogName, enter dynamodb-lambda-func.
  4. Leave the remaining values at their defaults.
  5. Select I acknowledge that this app creates custom IAM roles and resource policies.
  6. Choose Deploy.

You’re returned to the Connect data sources section on the Athena console.

  1. Choose the refresh icon next to Lambda function.
  2. Choose the Lambda function you just created (dynamodb-lambda-func).

  1. Choose Next.
  2. Review the settings and choose Create data source.
  3. If you haven’t already set up the Athena query results location, choose View settings on the Athena query editor page.

  1. Choose Manage.
  2. For Location of query result, browse to the S3 bucket specified for the Athena spill bucket in the CloudFormation template.
  3. Add Athena-query to the S3 path.
  4. Choose Save.

  1. In the Athena query editor, for Data source, choose DDB.
  2. For Database, choose default.

You can now explore the schema for the sportseventinfo table; the data is the same in DynamoDB.

  1. Choose the options icon for the sportseventinfo table and choose Preview Table.

Create the Amazon RDS for MySQL data source connector

Now let’s create the connector for Amazon RDS for MySQL.

  1. On the Athena console, choose Data sources in the navigation pane.
  2. Choose Create data source.
  3. For Data sources, select MySQL.
  4. Choose Next.

  1. For Data source name, enter MySQL.

  1. For Lambda function, choose Create Lambda function.

  1. For Application name, enter AthenaMySQLConnector.
  2. For SecretNamePrefix, enter AthenaMySQLFederation.
  3. For SpillBucket, enter the value from the CloudFormation stack for AthenaSpillBucket.
  4. For DefaultConnectionString, enter the value from the CloudFormation stack for MySQLConnection.
  5. For LambdaFunctionName, enter mysql-lambda-func.
  6. For SecurityGroupIds, enter the value from the CloudFormation stack for RDSSecurityGroup.
  7. For SubnetIds, enter the value from the CloudFormation stack for RDSSubnets.
  8. Select I acknowledge that this app creates custom IAM roles and resource policies.
  9. Choose Deploy.

  1. On the Lambda console, open the function you created (mysql-lambda-func).
  2. On the Configuration tab, under Environment variables, choose Edit.

  1. Choose Add environment variable.
  2. Enter a new key-value pair:
    • For Key, enter MYSQL_connection_string.
    • For Value, enter the value from the CloudFormation stack for MySQLConnection.
  3. Choose Save.

  1. Return to the Connect data sources section on the Athena console.
  2. Choose the refresh icon next to Lambda function.
  3. Choose the Lambda function you created (mysql-lamdba-function).

  1. Choose Next.
  2. Review the settings and choose Create data source.
  3. In the Athena query editor, for Data Source, choose MYSQL.
  4. For Database, choose sportsdata.

  1. Choose the options icon by the tables and choose Preview Table to examine the data and schema.

In the following sections, we demonstrate different ways to optimize our queries.

Optimal join order using EXPLAIN plan

A join is a basic SQL operation to query data on multiple tables using relations on matching columns. Join operations affect how much data is read from a table, how much data is transferred to the intermediate stages through networks, and how much memory is needed to build up a hash table to facilitate a join.

If you have multiple join operations and these join tables aren’t in the correct order, you may experience performance issues. To demonstrate this, we use the following tables from difference sources and join them in a certain order. Then we observe the query runtime and improve performance by using the EXPLAIN feature from Athena, which provides some suggestions for optimizing the query.

The CloudFormation template you ran earlier loaded data into the following services:

AWS Storage Table Name Number of Rows
Amazon DynamoDB sportseventinfo 657
Amazon S3 person 7,025,585
Amazon S3 ticketinfo 2,488

Let’s construct a query to find all those who participated in the event by type of tickets. The query runtime with the following join took approximately 7 mins to complete:

SELECT t.id AS ticket_id, 
e.eventid, 
p.first_name 
FROM 
"DDB"."default"."sportseventinfo" e, 
"AwsDataCatalog"."athenablog"."person" p, 
"AwsDataCatalog"."athenablog"."ticketinfo" t 
WHERE 
t.sporting_event_id = cast(e.eventid as double) 
AND t.ticketholder_id = p.id

Now let’s use EXPLAIN on the query to see its run plan. We use the same query as before, but add explain (TYPE DISTRIBUTED):

EXPLAIN (TYPE DISTRIBUTED)
SELECT t.id AS ticket_id, 
e.eventid, 
p.first_name 
FROM 
"DDB"."default"."sportseventinfo" e, 
"AwsDataCatalog"."athenablog"."person" p, 
"AwsDataCatalog"."athenablog"."ticketinfo" t 
WHERE 
t.sporting_event_id = cast(e.eventid as double) 
AND t.ticketholder_id = p.id

The following screenshot shows our output

Notice the cross-join in Fragment 1. The joins are converted to a Cartesian product for each table, where every record in a table is compared to every record in another table. Therefore, this query takes a significant amount of time to complete.

To optimize our query, we can rewrite it by reordering the joining tables as sportseventinfo first, ticketinfo second, and person last. The reason for this is because the WHERE clause, which is being converted to a JOIN ON clause during the query plan stage, doesn’t have the join relationship between the person table and sportseventinfo table. Therefore, the query plan generator converted the join type to cross-joins (a Cartesian product), which less efficient. Reordering the tables aligns the WHERE clause to the INNER JOIN type, which satisfies the JOIN ON clause and runtime is reduced from 7 minutes to 10 seconds.

The code for our optimized query is as follows:

SELECT t.id AS ticket_id, 
e.eventid, 
p.first_name 
FROM 
"DDB"."default"."sportseventinfo" e, 
"AwsDataCatalog"."athenablog"."ticketinfo" t, 
"AwsDataCatalog"."athenablog"."person" p 
WHERE 
t.sporting_event_id = cast(e.eventid as double) 
AND t.ticketholder_id = p.id

The following is the EXPLAIN output of our query after reordering the join clause:

EXPLAIN (TYPE DISTRIBUTED) 
SELECT t.id AS ticket_id, 
e.eventid, 
p.first_name 
FROM 
"DDB"."default"."sportseventinfo" e, 
"AwsDataCatalog"."athenablog"."ticketinfo" t, 
"AwsDataCatalog"."athenablog"."person" p 
WHERE t.sporting_event_id = cast(e.eventid as double) 
AND t.ticketholder_id = p.id

The following screenshot shows our output.

The cross-join changed to INNER JOIN with join on columns (eventid, id, ticketholder_id), which results in the query running faster. Joins between the ticketinfo and person tables converted to the PARTITION distribution type, where both left and right tables are hash-partitioned across all worker nodes due to the size of the person table. The join between the sportseventinfo table and ticketinfo are converted to the REPLICATED distribution type, where one table is hash-partitioned across all worker nodes and the other table is replicated to all worker nodes to perform the join operation.

For more information about how to analyze these results, refer to Understanding Athena EXPLAIN statement results.

As a best practice, we recommend having a JOIN statement along with an ON clause, as shown in the following code:

SELECT t.id AS ticket_id, 
e.eventid, 
p.first_name 
FROM 
"AwsDataCatalog"."athenablog"."person" p 
JOIN "AwsDataCatalog"."athenablog"."ticketinfo" t ON t.ticketholder_id = p.id 
JOIN "ddb"."default"."sportseventinfo" e ON t.sporting_event_id = cast(e.eventid as double)

Also as a best practice when you join two tables, specify the larger table on the left side of join and the smaller table on the right side of the join. Athena distributes the table on the right to worker nodes, and then streams the table on the left to do the join. If the table on the right is smaller, then less memory is used and the query runs faster.

In the following sections, we present examples of how to optimize pushdowns for filter predicates and projection filter operations for the Athena data source using EXPLAIN ANALYZE.

Pushdown optimization for the Athena connector for Amazon RDS for MySQL

A pushdown is an optimization to improve the performance of a SQL query by moving its processing as close to the data as possible. Pushdowns can drastically reduce SQL statement processing time by filtering data before transferring it over the network and filtering data before loading it into memory. The Athena connector for Amazon RDS for MySQL supports pushdowns for filter predicates and projection pushdowns.

The following table summarizes the services and tables we use to demonstrate a pushdown using Aurora MySQL.

Table Name Number of Rows Size in KB
player_partitioned 5,157 318.86
sport_team_partitioned 62 5.32

We use the following query as an example of a filtering predicate and projection filter:

SELECT full_name,
name 
FROM "sportsdata"."player_partitioned" a 
JOIN "sportsdata"."sport_team_partitioned" b ON a.sport_team_id=b.id 
WHERE a.id='1.0'

This query selects the players and their team based on their ID. It serves as an example of both filter operations in the WHERE clause and projection because it selects only two columns.

We use EXPLAIN ANALYZE to get the cost for the running this query:

EXPLAIN ANALYZE 
SELECT full_name,
name 
FROM "MYSQL"."sportsdata"."player_partitioned" a 
JOIN "MYSQL"."sportsdata"."sport_team_partitioned" b ON a.sport_team_id=b.id 
WHERE a.id='1.0'

The following screenshot shows the output in Fragment 2 for the table player_partitioned, in which we observe that the connector has a successful pushdown filter on the source side, so it tries to scan only one record out of the 5,157 records in the table. The output also shows that the query scan has only two columns (full_name as the projection column and sport_team_id and the join column), and uses SELECT and JOIN, which indicates the projection pushdown is successful. This helps reduce the data scan when using Athena data source connectors.

Now let’s look at the conditions in which a filter predicate pushdown doesn’t work with Athena connectors.

LIKE statement in filter predicates

We start with the following example query to demonstrate using the LIKE statement in filter predicates:

SELECT * 
FROM "MYSQL"."sportsdata"."player_partitioned" 
WHERE first_name LIKE '%Aar%'

We then add EXPLAIN ANALYZE:

EXPLAIN ANALYZE 
SELECT * 
FROM "MYSQL"."sportsdata"."player_partitioned" 
WHERE first_name LIKE '%Aar%'

The EXPLAIN ANALYZE output shows that the query performs the table scan (scanning the table player_partitioned, which contains 5,157 records) for all the records even though the WHERE clause only has 30 records matching the condition %Aar%. Therefore, the data scan shows the complete table size even with the WHERE clause.

We can optimize the same query by selecting only the required columns:

EXPLAIN ANALYZE 
SELECT sport_team_id,
full_name 
FROM "MYSQL"."sportsdata"."player_partitioned" 
WHERE first_name LIKE '%Aar%'

From the EXPLAIN ANALYZE output, we can observe that the connector supports the projection filter pushdown, because we select only two columns. This brought the data scan size down to half of the table size.

OR statement in filter predicates

We start with the following query to demonstrate using the OR statement in filter predicates:

SELECT id,
first_name 
FROM "MYSQL"."sportsdata"."player_partitioned" 
WHERE first_name = 'Aaron' OR id ='1.0'

We use EXPLAIN ANALYZE with the preceding query as follows:

EXPLAIN ANALYZE 
SELECT * 
FROM 
"MYSQL"."sportsdata"."player_partitioned" 
WHERE first_name = 'Aaron' OR id ='1.0'

Similar to the LIKE statement, the following output shows that query scanned the table instead of pushing down to only the records that matched the WHERE clause. This query outputs only 16 records, but the data scan indicates a complete scan.

Pushdown optimization for the Athena connector for DynamoDB

For our example using the DynamoDB connector, we use the following data:

Table Number of Rows Size in KB
sportseventinfo 657 85.75

Let’s test the filter predicate and project filter operation for our DynamoDB table using the following query. This query tries to get all the events and sports for a given location. We use EXPLAIN ANALYZE for the query as follows:

EXPLAIN ANALYZE 
SELECT EventId,
Sport 
FROM "DDB"."default"."sportseventinfo" 
WHERE Location = 'Chase Field'

The output of EXPLAIN ANALYZE shows that the filter predicate retrieved only 21 records, and the project filter selected only two columns to push down to the source. Therefore, the data scan for this query is less than the table size.

Now let’s see where filter predicate pushdown doesn’t work. In the WHERE clause, if you apply the TRIM() function to the Location column and then filter, predicate pushdown optimization doesn’t apply, but we still see the projection filter optimization, which does apply. See the following code:

EXPLAIN ANALYZE 
SELECT EventId,
Sport 
FROM "DDB"."default"."sportseventinfo" 
WHERE trim(Location) = 'Chase Field'

The output of EXPLAIN ANALYZE for this query shows that the query scans all the rows but is still limited to only two columns, which shows that the filter predicate doesn’t work when the TRIM function is applied.

We’ve seen from the preceding examples that the Athena data source connector for Amazon RDS for MySQL and DynamoDB do support filter predicates and projection predicates for pushdown optimization, but we also saw that operations such as LIKE, OR, and TRIM when used in the filter predicate don’t support pushdowns to the source. Therefore, if you encounter unexplained charges in your federated Athena query, we recommend using EXPLAIN ANALYZE with the query and determine whether your Athena connector supports the pushdown operation or not.

Please note that running EXPLAIN ANALYZE incurs cost because it scans the data.

Conclusion

In this post, we showcased how to use EXPLAIN and EXPLAIN ANALYZE to analyze Athena SQL queries for data sources on AWS S3 and Athena federated SQL query for data source like DynamoDB and Amazon RDS for MySQL. You can use this as an example to optimize queries which would also result in cost savings.


About the Authors

Nishchai JM is an Analytics Specialist Solutions Architect at Amazon Web services. He specializes in building Big-data applications and help customer to modernize their applications on Cloud. He thinks Data is new oil and spends most of his time in deriving insights out of the Data.

Varad Ram is Senior Solutions Architect in Amazon Web Services. He likes to help customers adopt to cloud technologies and is particularly interested in artificial intelligence. He believes deep learning will power future technology growth. In his spare time, he like to be outdoor with his daughter and son.