Tag Archives: Amazon S3

Securing your Amazon S3 buckets: Identifying and remediating over-permissioned access

Post Syndicated from Hetal Kolekar original https://aws.amazon.com/blogs/security/securing-your-amazon-s3-buckets-identifying-and-remediating-over-permissioned-access/

Misconfigured Amazon Simple Storage Service (Amazon S3) buckets can expose your data to unauthorized access. Without proactive review, S3 bucket policies or Access Control Lists (ACLs) configured with broad access may go unnoticed in your environment. In this post, you learn how to identify and fix over-permissioned S3 buckets across your AWS environment, along with best practice recommendations and automation opportunities to help you prevent security gaps. This post provides a workflow framework and methodology recommendations for your security team to adapt. The focus of this post is on the what and why rather than a prescriptive implementation. You will need to customize the approach based on your organization’s requirements and existing security tooling.

This solution is intended for security engineers, cloud architects, and DevOps teams managing single- or multiple-account AWS environments with Amazon S3 workloads that require access management.

Prerequisites

Before you begin, make sure you have the following in place:

Solution overview

This solution uses a five-phase workflow diagram to detect, remediate, and continuously monitor over-permissioned S3 buckets across your AWS accounts. The following workflow diagram illustrates the high-level end-to-end process for identifying and remediating over-permissioned S3 buckets across your Amazon Web Services (AWS) environment.
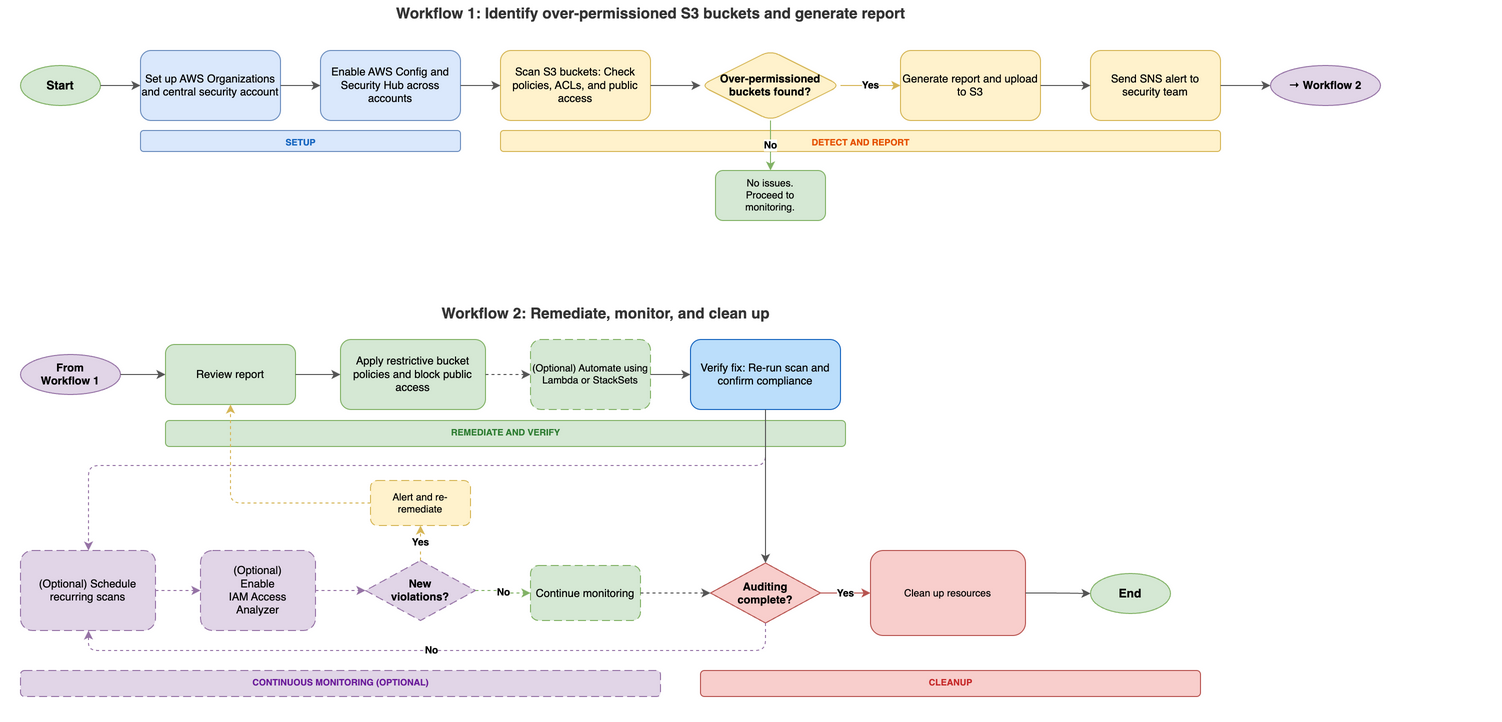
Figure 1: Amazon S3 over-permissive access – Detection, remediation, monitoring and cleanup workflow

Figure 1: Amazon S3 over-permissive access – Detection, remediation, monitoring and cleanup workflow

The diagram in Figure 1 consists of five phases:

  1. Setup and prerequisites – Configure AWS Organizations or multi-account access, designate a central security account, deploy AWS Config across all accounts, and enable AWS Security Hub with a central administrator.
  2. Detection and identification – Deploy AWS Config rules (such as s3-bucket-public-read-prohibited and s3-bucket-public-write-prohibited) and run an audit Lambda function that scans each S3 bucket. The function checks three areas: Public Access Block configuration, bucket policy status, and bucket ACL grants. Buckets with issues are added to a risky buckets list. The function then generates a report in CSV and JSON format, uploads it to an output S3 bucket, and sends an SNS alert.
  3. Remediation – Address findings using one or more approaches – Apply restrictive bucket policies to deny public read/write access and restrict access to specific IAM principals; deploy a remediation Lambda function to automatically update bucket policies and disable public access settings; or use CloudFormation StackSets to deploy standardized policies across multiple accounts.
  4. Continuous monitoring – Schedule the audit Lambda function for recurring scans (daily or weekly) using Amazon EventBridge. Use EventBridge to detect policy changes, configure automated notifications for new violations, enable IAM Access Analyzer for S3 to identify external access, and run regular compliance scans.
  5. Resource cleanup – Review and delete resources created during the audit that are no longer needed, including Lambda functions and IAM roles, EventBridge rules, SNS topics and subscriptions, audit output S3 buckets, AWS Config rules, and Security Hub (if enabled only for this audit).

Cost considerations

This section covers the AWS services used in this solution and their associated costs so you can estimate spend before deployment. The primary cost drivers are AWS Config and Security Hub, which scale with the number of accounts and resources you monitor. Lambda, Amazon EventBridge, Amazon SNS, and Amazon S3 typically add minimal costs for most environments. Start with a pilot in one or two accounts to validate costs before scaling.

  • AWS Config – Charges per configuration item recorded and per rule evaluation. Costs scale with the number of accounts and resources tracked.
  • Security Hub – Charges per account per AWS Region for security checks and finding ingestion.
  • Lambda – Charges per request and per GB-second of compute time.
  • EventBridge – Scheduled rules are free. Custom event bus usage might incur charges.
  • Amazon SNS – Charges per notification delivered.
  • Amazon S3 – Storage costs for audit report output files. Minimal for most environments.
  • AWS IAM Access Analyzer – Check the AWS IAM Access Analyzer pricing page to understand which features have costs associated with them.

Check the service pricing pages for current rates. Use the AWS Pricing Calculator to estimate costs for your specific environment before enabling services across all accounts. Consider starting with a pilot in one or two accounts to validate costs before scaling.

Detect and report over-permissioned buckets

This section walks you through setting up the audit environment, deploying the Lambda-based scanner, and generating reports of over-permissioned S3 buckets across your accounts. Follow these steps to identify over-permissioned S3 buckets in your multi-account environment, starting with preparing your environment for an Amazon S3 audit.

To set up the multi-account audit environment:

  1. Set up AWS Organizations or multi-account access. Set up centralized management of your AWS accounts using AWS Organizations or configure cross-account IAM roles.
  2. Choose a central security account. Choose one account as your security/audit account. This account will run the audit Lambda function and collect results from member accounts.
  3. Create an Amazon SNS topic for alerts. Subscribe your security team to receive notifications when over-permissioned buckets are detected. Note the topic Amazon Resource Name (ARN) from the output—you will need it when creating the Lambda execution role (step 6) and the Lambda function (step 9). Confirm the email subscription before testing; Amazon SNS doesn’t deliver alerts until the subscription is confirmed. Learn more in the Amazon SNS Developer Guide.
  4. (Optional): Create an S3 bucket for audit reports. If you plan to use Script v2 for historical reporting and trend analysis, create a dedicated bucket now. Skip this step if you only need real-time alerts using Script v1.
  5. Plan cross-account IAM roles. The central security account needs permission to scan member accounts. Design cross-account roles that:
    1. Grant minimum Amazon S3 read permissions (list buckets, read policies, ACLs, public access configurations).
    2. Include an external ID condition to mitigate the confused deputy problem.
    3. Can be deployed consistently using AWS CloudFormation StackSets.
    4. See the IAM documentation on creating cross-account roles, The confused deputy problem, and IAM security best practices for additional guidance on role configuration and trust policies.

      Note: The specific trust policy and permissions policy for your cross-account roles will depend on organizational requirements. Work with your IAM administrators to grant minimum necessary access for the audit function.

  6. Create the Lambda execution role. Create an IAM role for your Lambda function with the permissions it needs to scan buckets, publish alerts, and write logs. Apply the principle of least privilege—grant only the minimum Amazon S3 read permissions required for the audit (such as, listing buckets, reading bucket policies, ACLs, and public access block configurations), Amazon SNS publish permission for the alert topic created in step 3, Amazon S3 write permission for the output bucket created in step 4 (Script v2), and Amazon CloudWatch Logs permissions. For multi-account scanning, also include sts:AssumeRolepermission for the cross-account role ARNs created in step 5. The AWS Lambda execution role documentation has instructions on creating and configuring execution roles.
  7. To deploy the S3 audit solution Deploy the audit components
    1. Enable AWS Config in member accounts. AWS Config provides compliance monitoring and can detect when S3 buckets are created or modified with public access settings. This will enable the Lambda-based audit to receive real-time detection between scheduled scans. The AWS Config Developer Guide has setup instructions. Deploy pre-defined AWS Config rules to identify overly permissive settings. These managed rules provide automated compliance checking. When AWS Config detects violations, it sends findings to Security Hub (configured in step 8) for centralized visibility alongside the Lambda audit results.
      • s3-bucket-public-read-prohibited
      • s3-bucket-public-write-prohibited
      • Create AWS Config rules for specific permission patterns. For the full list of available rules, see the AWS Config managed rules reference
  8. Enable Security Hub for centralized visibility. Enable AWS Security Hub in member accounts and configure the central security account as the administrator. Security Hub aggregates findings from AWS Config rules (step 7), IAM Access Analyzer (enabled later), and can receive custom findings from your Lambda audit function, providing a single dashboard for Amazon S3 security issues across your organization. See the Security Hub User Guide for setup details.
  9. Deploy the audit Lambda function. Deploy a Python Lambda function using the Boto3 library to list S3 buckets, check their policies, ACLs, and IAM permissions, and identify over-permissioned buckets. See the example scripts that follow.

Important: These code examples aren’t production ready. Adapt them to meet your organization’s requirements and test them in a non-production environment before deployment.

Choose your approach:

  • Script v1 – Best for immediate SNS alerts when issues are detected.
  • Script v2 – Best for historical reports, trend analysis using BI tools.
  • Both scripts – Best for different schedules and ongoing needs.

Audit Lambda function – Example script v1 (Scan and alert)

The following is an example of a Lambda function script for reference purposes. Review, adapt, and test before use in your environment, it scans all S3 buckets in the current account and checks for:

  • Public Access block configuration gaps
  • Bucket policies that allow public access
  • ACL grants to AllUsers

Note: Replace placeholder values with actual values before deployment:

  • <REGION>– Your AWS Region (for example, us-east-1)
  • <ACCOUNT_ID>– Your 12-digit AWS account ID
  • <TOPIC_NAME>– The name of your SNS topic created in step 3
import boto3
import json

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    sns = boto3.client('sns')
    risky_buckets = []
    errors = []

    try:
        buckets = s3.list_buckets()['Buckets']
    except Exception as e:
        return {'statusCode': 500, 'body': f'Failed to list buckets: {str(e)}'}

    for bucket in buckets:
        bucket_name = bucket['Name']
        issues = []

        try:
            # Check Public Access Block — all four settings should be enabled
            try:
                pab = s3.get_public_access_block(Bucket=bucket_name)
                config = pab['PublicAccessBlockConfiguration']
                if not all([
                    config.get('BlockPublicAcls'),      # Block new public ACLs
                    config.get('BlockPublicPolicy'),     # Block new public bucket policies
                    config.get('IgnorePublicAcls'),      # Ignore existing public ACLs
                    config.get('RestrictPublicBuckets')   # Restrict access to public buckets
                ]):
                    issues.append('Public Access Block not fully enabled')
            except s3.exceptions.NoSuchPublicAccessBlockConfiguration:
                issues.append('No Public Access Block configured')

            # Check bucket policy — flag if policy status is public
            try:
                policy_status = s3.get_bucket_policy_status(Bucket=bucket_name)
                if policy_status['PolicyStatus']['IsPublic']:
                    issues.append('Bucket policy allows public access')
            except s3.exceptions.NoSuchBucketPolicy:
                pass  # No bucket policy is acceptable

            # Check bucket ACL
            acl = s3.get_bucket_acl(Bucket=bucket_name)
            for grant in acl.get('Grants', []):
                grantee = grant.get('Grantee', {})
                uri = grantee.get('URI', '')
                # 'AllUsers' = anonymous public access
                # 'AuthenticatedUsers' = any AWS account (still overly permissive)
                if grantee.get('Type') == 'Group' and ('AllUsers' in uri or 'AuthenticatedUsers' in uri):
                    issues.append('Bucket ACL grants public access')
                    break

            if issues:
                risky_buckets.append({'bucket': bucket_name, 'issues': issues})

        except Exception as e:
            errors.append(f'{bucket_name}: {str(e)}')

    # Send alert if risky buckets found
    if risky_buckets:
        message = f'Found {len(risky_buckets)} buckets with public access:\n\n'
        for item in risky_buckets:
            message += f"  {item['bucket']}: {', '.join(item['issues'])}\n"

        sns.publish(
            TopicArn='arn:aws:sns:<REGION>:<ACCOUNT_ID>:<TOPIC_NAME>',
            Subject='S3 Public Access Alert',
            Message=message
        )

    return {
        'statusCode': 200,
        'body': json.dumps({
            'risky_buckets': risky_buckets,
            'errors': errors,
            'total_checked': len(buckets)
        })
    }

Multi-account scanning: This script scans the current account only. To scan across member accounts, see the Multi-account extension section later in this post.

Audit Lambda function – Example script v2 (CSV and JSON report)

The following is an example Lambda function script for reference purposes. Before deploying any script, review error handling, logging, output structure, and permissions. This script generates CSV and JSON output files and uploads them to an S3 bucket for reporting and business intelligence (BI) dashboard integration.

You can deploy both functions with different EventBridge schedules, for example, Script v1 daily for alerts and Script v2 weekly for reports.

Note: Before you deploy this script, replace <OUTPUT_BUCKET_NAME> with the S3 bucket you created for audit reports in step 4.

import boto3
import csv
import json
import os

def lambda_handler(event, context):
    s3 = boto3.client('s3')
    buckets = s3.list_buckets()['Buckets']

    full_access_buckets = []
    for bucket in buckets:
        bucket_name = bucket['Name']
        try:
            bucket_policy = s3.get_bucket_policy(Bucket=bucket_name)['Policy']
            policy = json.loads(bucket_policy)
            for statement in policy['Statement']:
                if (statement['Effect'] == 'Allow'
                    and statement['Principal'] == '*'
                    and 'Action' in statement
                    and 's3:*' in statement['Action']):
                    full_access_buckets.append({'BucketName': bucket_name})
                    break
        except s3.exceptions.ClientError as e:
            if e.response['Error']['Code'] != 'NoSuchBucketPolicy':
                print(f'Error checking bucket policy for {bucket_name}: {e}')

    # Output CSV
    csv_output = os.path.join('/tmp', 'full_access_buckets.csv')
    with open(csv_output, 'w', newline='') as csvfile:
        writer = csv.DictWriter(csvfile, fieldnames=['BucketName'])
        writer.writeheader()
        writer.writerows(full_access_buckets)

    # Output JSON
    json_output = os.path.join('/tmp', 'full_access_buckets.json')
    with open(json_output, 'w') as jsonfile:
        json.dump(full_access_buckets, jsonfile, indent=2)

    # Upload to Amazon S3
    output_bucket = '<OUTPUT_BUCKET_NAME>'
    s3.upload_file(csv_output, output_bucket, 'full_access_buckets.csv')
    s3.upload_file(json_output, output_bucket, 'full_access_buckets.json')

    return {
        'statusCode': 200,
        'body': json.dumps(f'CSV and JSON files uploaded to {output_bucket}')
    }

Important: If this function runs on a schedule, consider implementing a file naming strategy with timestamps to prevent overwriting previous reports or establish a lifecycle policy to manage retention. Include the output bucket in your cleanup procedures when the auditing process is no longer needed.

What if no over-permissioned buckets are found?

If the audit scan returns zero risky buckets, document the clean baseline for future comparison and move to the verification and monitoring phase to so new buckets or policy changes don’t introduce risk over time.

Multi-account extension

The preceding example scripts scan buckets in the current account only. To scan across member accounts in your organization, add the following AssumeRole logic. This function assumes the cross-account IAM role you created during setup, then returns an Amazon S3 client with temporary credentials for each member account.

Note: Before you deploy, configure the following Lambda environment variables:

  • <MEMBER_ACCOUNTS> – Comma-separated list of 12-digit account IDs to scan (for example, 111111111111,222222222222)
  • <CROSS_ACCOUNT_ROLE_NAME> – The IAM role name created in each member account (for example, S3AuditRole)
  • <EXTERNAL_ID> – The external ID configured in the trust policy (for example, s3-audit-external-id)
import boto3
import os

def get_member_s3_clients():
    """
    Assumes the cross-account audit role in each member account
    and returns a list of (account_id, s3_client) tuples.
    """
    sts = boto3.client('sts')
    member_accounts = os.environ.get('<MEMBER_ACCOUNTS>', '').split(',')
    cross_account_role_name = os.environ.get('<CROSS_ACCOUNT_ROLE_NAME>')
    external_id = os.environ.get('<EXTERNAL_ID>')

    clients = []
    for account_id in member_accounts:
        account_id = account_id.strip()
        if not account_id:
            continue

        try:
            assumed_role = sts.assume_role(
                RoleArn=f'arn:aws:iam::{account_id}:role/{cross_account_role_name}',
                RoleSessionName='S3AuditSession',
                ExternalId=external_id
            )

            # Create S3 client with assumed credentials
            s3_client = boto3.client(
                's3',
                aws_access_key_id=assumed_role['Credentials']['AccessKeyId'],
                aws_secret_access_key=assumed_role['Credentials']['SecretAccessKey'],
                aws_session_token=assumed_role['Credentials']['SessionToken']
            )
            clients.append((account_id, s3_client))

        except Exception as e:
            print(f'Failed to assume role in account {account_id}: {e}')

    return clients

To scan each member account, replace the single-account s3.list_buckets() call with a loop over member accounts:

def lambda_handler(event, context):
    all_risky_buckets = []
    all_errors = []

    # Scan each member account
    for account_id, s3_client in get_member_s3_clients():
        try:
            buckets = s3_client.list_buckets()['Buckets']
            for bucket in buckets:
                # ... same scanning logic as the single-account scripts ...
                # Use s3_client instead of s3 for each API call
                pass
        except Exception as e:
            all_errors.append(f'Account {account_id}: {e}')

    # ... same alerting/reporting logic ...

The Lambda execution role in the central security account needs sts:AssumeRole permission for the cross-account role ARNs. Add this to the execution role policy you created in step 5.

Remediate elevated access

This section describes how to fix over-permissioned buckets using account-level controls, bucket policies, and optional automation. Any elevated access that you find needs to be remediated.

Enable Amazon S3 Block Public Access (account level)

Before applying individual bucket policies, enable Amazon S3 Block Public Access at the account level. This prevents buckets in the account from being made public, regardless of individual bucket policies or ACLs. See theS3 Block Public Access documentation for configuration details. See the following example AWS CLI command; replace <ACCOUNT_ID> with the ID of the account you’re using to manage resource access:

aws s3control put-public-access-block \
  --account-id <ACCOUNT_ID> \
  --public-access-block-configuration \
BlockPublicAcls=true,IgnorePublicAcls=true,BlockPublicPolicy=true,RestrictPublicBuckets=true

For multi-account environments, deploy this setting across member accounts using AWS CloudFormation StackSets or AWS Organizations service control policies (SCPs).

Important: Before enabling account-level S3 Block Public Access, check whether any workloads need public bucket access (for example, static website hosting, public dataset sharing). Coordinate with your application teams to identify any exceptions.

Remediate using bucket policies

Implement bucket policies that restrict access to specific IAM users, roles, or accounts. When crafting policies, apply the principle of least privilege and include only the actions and principals required for your use case.

Example S3 bucket policy: deny public read/write access. Modify the resource ARN, actions, and conditions to match your requirements:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Deny",
      "Principal": "*",
      "Action": [
        "s3:PutObject", "s3:PutObjectAcl",
        "s3:GetObject", "s3:GetObjectAcl",
        "s3:DeleteObject"
      ],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>/*",
      "Condition": {
        "StringEquals": {
          "s3:x-amz-acl": ["public-read", "public-read-write"]
        }
      }
    }
  ]
}

Example S3 bucket policy: restrict access to specific IAM principals. Replace <ACCOUNT_ID>, <USERNAME>, and <ROLE_NAME>:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowObjectAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::<ACCOUNT_ID>:user/<USERNAME>",
          "arn:aws:iam::<ACCOUNT_ID>:role/<ROLE_NAME>"
        ]
      },
      "Action": ["s3:GetObject", "s3:PutObject", "s3:DeleteObject"],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>/*"
    },
    {
      "Sid": "AllowBucketAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::<ACCOUNT_ID>:user/<USERNAME>",
          "arn:aws:iam::<ACCOUNT_ID>:role/<ROLE_NAME>"
        ]
      },
      "Action": ["s3:ListBucket", "s3:GetBucketLocation"],
      "Resource": "arn:aws:s3:::<BUCKET_NAME>"
    }
  ]
}

See the Amazon S3 bucket policy documentation for additional examples and guidance.

Automate remediation with Lambda or CloudFormation StackSets (optional):

You can also remediate using Lambda or CloudFormation Stacksets:

  • Create Lambda functions to automatically update bucket policies or disable public access settings for flagged buckets
  • Use CloudFormation StackSets to deploy standardized bucket policies and S3 Block Public Access settings across multiple accounts

Verify your remediation

This section explains how to confirm that your fixes are effective before moving to ongoing monitoring. After applying remediation, verify the fix is effective before setting up ongoing monitoring:

  1. Re-run the audit Lambda function – Confirm the previously flagged buckets no longer appear in the risky buckets list.
  2. Check Security Hub compliance – Verify the compliance status has changed from FAILED to PASSED for Amazon S3-related controls.
  3. Validate with IAM Access Analyzer – Review findings for the remediated S3 buckets. Active findings should resolve automatically after public access is removed.
  4. Test application functionality – Confirm that legitimate workloads continue to function correctly.

Document the verification results for your auditing needs. If any S3 buckets still show issues, investigate whether the policy was applied correctly or if there are conflicting permissions.

Automation opportunities

This section covers optional strategies to automate ongoing detection and maintain your security posture without manual intervention.

  1. (Optional) Schedule recurring scans with Amazon EventBridge
    • Regular security scans help identify new issues arising from configuration changes or newly created S3 buckets. When new security risks are detected, Amazon SNS sends an alert and automatically initiates the remediation phase (Workflow 2 in Figure 1). To avoid repeated alerts, you can configure the audit Lambda function to run on a schedule and compare current results with the previous baseline to generate notifications when new findings are discovered.
    • For ongoing monitoring, you can schedule the audit Lambda function to run on a recurring basis using EventBridge. Create a scheduled rule with a cron expression (for example, daily at 6:00 AM UTC or weekly on Mondays), add the Lambda function as the target, and grant EventBridge permission to invoke it. See Amazon EventBridge scheduling documentation for instructions on creating scheduled rules and configuring targets.
  2. Enable IAM Access Analyzer for Amazon S3
    • IAM Access Analyzer monitors bucket policies, ACLs, and access points to identify buckets accessible from outside your account or organization. Create an analyzer scoped to your organization or individual account, then review findings to identify unintended external access. Findings automatically flow into Security Hub when both services are enabled, giving you a dashboard view for Amazon S3 security findings. See the IAM Access Analyzer documentation for setup and usage instructions.
  3. Automate notifications for policy drift
    • Recurring scans might surface new findings from policy drift or newly created buckets. When new risks are detected, Amazon SNS alert triggers and the remediation cycle repeat (as shown in Workflow 2 in Figure 1) sends email notifications. Configure the audit Lambda function to compare current scan results against the previous baseline and alert on new findings for ongoing reviews.

Clean up

This section lists the resources created during this walkthrough that you should review and remove when they are no longer needed. If the following services were not previously active in your account, leaving them enabled might result in additional ongoing charges. See the Cost considerations section for details. Review and remove unused resources to optimize costs.

Delete or disable the following script-generated resources if they’re not required after outputs are generated. Focus first on Lambda functions and EventBridge rules if you’re not running recurring scans. If you enabled AWS Config or Security Hub specifically for this audit, evaluate whether you need them for other compliance requirements before disabling.

  • Lambda – Functions, IAM roles, and policies created for auditing
  • Amazon EventBridge – Scheduled rules created for recurring audit triggers
  • Amazon SNS – Topics and subscriptions created for notifications
  • Amazon S3 – Buckets containing script-generated audit output files
  • AWS Config – Rules and recorders if no longer needed for compliance
  • Security Hub – Disable if enabled solely for this audit
  • IAM Access Analyzer – Delete the analyzer if no longer needed for ongoing monitoring

Note: Be careful when deleting data and consider temporarily disabling services first to check for dependencies. Only delete resources generated as part of your audit outputs. Verify you have retained any necessary results before proceeding. Verify resources are not used by other workloads before deletion.

Best practices

This section provides recommendations to maintain secure Amazon S3 configurations long-term. To learn more about maintaining secure Amazon S3 configurations, review the AWS documentation links provided in the conclusion. The following recommendations aren’t exhaustive. Adapt and extend them based on your organization’s evolving security requirements and AWS best practices guidance. After you’ve fixed existing issues, these practices help you maintain secure Amazon S3 configurations.

  • Start with account-level controls – Enable S3 Block Public Access at the account level. This prevents buckets from becoming public even if someone misconfigures an individual bucket policy. For multi-account environments, enforce this through AWS Organizations SCPs.
  • Automate detection – Use IAM Access Analyzer to detect external access. Schedule your audit Lambda function with EventBridge to catch new issues weekly or daily, depending on your change frequency. Compare scan results against previous baselines to identify drift.
  • Standardize across accounts – Use CloudFormation StackSets to deploy the same secure configuration to all accounts in your organization, reducing the chance of configuration drift. Use StackSets for IAM roles, AWS Config rules, and S3 Block Public Access settings.

Additional security measures

  • Regularly review and rotate cross-account IAM role credentials and external IDs
  • Implement Amazon S3 server-side encryption (SSE-S3 or SSE-KMS) for data at rest
  • Enable S3 access logging and AWS CloudTrail data events for audit trails

Conclusion

This section summarizes what you accomplished and suggests next steps to maintain your S3 security posture. By implementing the detection, remediation, and monitoring workflow outlined in this post, you can proactively identify and secure over-permissioned S3 buckets across your AWS environment. To maintain your ongoing security posture, enable IAM Access Analyzer for continuous monitoring and schedule recurring audits with EventBridge. To learn more about Amazon S3 security best practices, see Security best practices for Amazon S3

For more information:

If you have feedback about this post, submit comments in the Comments section below.

Hetal Kolekar

Hetal Kolekar

Hetal is a Sr. Technical Account Manager at AWS with more than 21 years of experience in Infrastructure Architecture, Security, Systems Engineering, and Consulting. He excels in leading teams to strengthen their cloud security posture and helps customers scale up their security using AWS services. Hetal is a guitarist and loves playing at church.

Manomayi Vedam

Manonmayi Vedam

Manonmayi is a Senior TAM and Product Owner at AWS, specializing in AI-driven cloud enablement, security, and generative AI risk across Healthcare, Financial Services, Energy, and Public Sector. She co-leads global security programs for Fortune 500 clients, contributes to the NIST Cyber AI Profile RMF and NCCoE, and is a Fellow at SCRS with recognition from GlobeeAwards and IEEE.

Fernando Freitas

Fernando Freitas

Fernando is a Sr. Technical Account Manager at AWS in Salt Lake City, focused on helping customers achieve their desired outcomes with the AWS Cloud. Fernando is passionate about Identity and Security, Training and Education.

Introducing self-managed Amazon S3 buckets for AWS Lambda function code

Post Syndicated from Doug Perkes original https://aws.amazon.com/blogs/compute/introducing-self-managed-amazon-s3-buckets-for-aws-lambda-function-code/

If you manage Lambda functions at scale, you’ve likely hit the 75 GB code storage limit or explained to your security team why deployment artifacts live in an S3 bucket you don’t control. Today, we’re announcing self-managed Amazon S3 buckets for AWS Lambda deployment packages. Lambda reads your code directly from your bucket, eliminating quota pressure and giving you full security control.

Previously, the default AWS-managed code storage created three challenges at scale. First, all copies count toward your 75 GB code storage quota. Second, you cannot apply your own encryption, access controls, or compliance tags to the internal bucket. Third, the copy cannot be incorporated into your disaster recovery strategies.

With self-managed S3 buckets, Lambda reads your function code directly from your bucket. No copy, no duplication. Your S3 object becomes the single source of truth for your functions. Deployment packages no longer count against your account’s code storage limit. You manage the bucket’s security and compliance posture: choosing the encryption, defining the access policies, managing lifecycle transitions, and maintaining the audit trail. And because you own the bucket, you can use S3 Cross-Region Replication to maintain fallback copies of your code in a secondary Region, so that your functions remain deployable even if your primary Region experiences an issue. Using self-managed S3 buckets also results in a faster time to first invoke for new functions and after function updates, because Lambda no longer needs to copy your zip package to a Lambda-managed S3 bucket.

You can use this feature today in all AWS standard regions where Lambda is available, at no additional charge beyond your standard Amazon S3 storage and request costs. Let’s look at some use cases, how it works, and how to use it at scale.

Use cases

Here are a few patterns where owning your deployment bucket makes a real difference.

CI/CD pipelines and artifact management

With self-managed storage, your CI/CD pipeline uploads once, and Lambda references the same object. One set of lifecycle rules and access controls covers all artifacts, and rollbacks mean pointing the function to a previous S3 object version.

Multi-account and multi-team architectures

Organizations using AWS Organizations often separate workloads into multiple accounts: a development account, a staging account, and a production account. They centralize shared resources in a tooling or shared-services account.

Self-managed buckets integrate naturally with this pattern:

  • Store all deployment artifacts in a central “artifact account” bucket.
  • Grant cross-account s3:GetObject access to Lambda execution roles in each workload account through bucket policies.
  • Maintain a single inventory of what code is deployed where, managed by your platform or DevOps team.
  • Enforce consistent encryption, versioning, and retention policies from one place.

Disaster recovery and business continuity

Because your deployment artifacts live in a bucket you own, you can use the built-in replication features of S3, Cross-Region Replication (CRR) or Same-Region Replication (SRR), to maintain copies of your code artifacts in backup locations. Combined with S3 Versioning and Object Lock, this gives you a durable, tamper-proof code archive that supports rapid recovery if a deployment is accidentally corrupted or deleted.

How it worked before

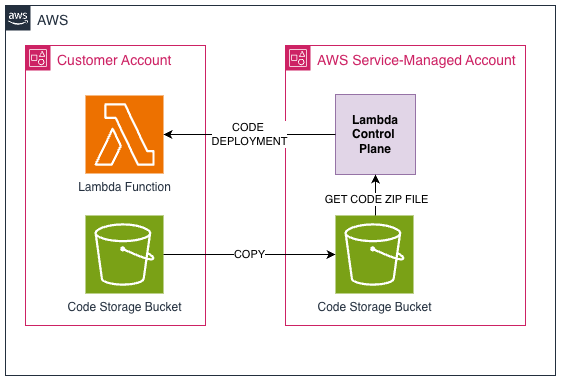
When you deploy a Lambda function using a .zip deployment package stored in Amazon S3, the process has traditionally worked like this:

  1. You upload your .zip deployment package to your S3 bucket.
  2. You call CreateFunction or UpdateFunctionCode, specifying the S3 bucket and S3 key.
  3. Lambda copies the .zip artifact from your bucket into an internal, service-managed bucket.
  4. Lambda uses this copy to create the optimized version of your function that runs at invocation time.
  5. The copied artifact counts toward your account’s 75 GB code storage quota.

Diagram showing standard Lambda deployment flow where Lambda copies the zip package to an internal bucket

Figure 1 — Standard Lambda deployment

This model is straightforward and works well for most workloads. However, it creates three friction points at scale:

  • Storage quota pressure: Every deployment package copy counts toward your account’s 75 GB total code storage limit. Organizations with hundreds of functions and multiple published versions can exhaust this quota.
  • No control over stored artifacts: You cannot configure encryption (beyond the service default), access logging, lifecycle policies, Object Lock, or compliance tags on the internal bucket.
  • Redundant storage: Your original artifact remains in your bucket while a copy lives in the Lambda bucket used for provisioning new instances of your Lambda function.

What’s new: REFERENCE mode

This launch introduced a new function configuration setting, S3ObjectStorageMode. The default value is COPY, which provides the existing behavior described in the preceding section. To enable self-managed S3 buckets, set S3ObjectStorageMode to REFERENCE when creating or updating a function. In this mode, Lambda no longer copies your deployment package. Instead, it stores a reference to your S3 object and reads the code directly from your bucket when needed. If you do not specify S3ObjectStorageMode, Lambda still takes a copy by default.

Diagram showing Lambda deployment with self-managed S3 storage where Lambda references the object directly

Figure 2 — Lambda deployment with self-managed storage

This gives you:

  • No quota consumption. Deployment packages in your bucket don’t count against the 75 GB Function and layer storage account limit.
  • Improved performance. Lambda no longer copies the code to an internal bucket, so function creation and updates are faster.
  • Full security and compliance control. Apply your own bucket policies, encryption, Object Lock, versioning, access logging, and compliance tags.
  • Single source of truth. Your S3 object is the canonical artifact with no additional copies and no drift.
  • Disaster recovery options. Use S3 Cross-Region Replication to maintain fallback copies in a secondary Region.

How it works

To use this feature, specify the S3ObjectStorageMode parameter when creating or updating your function.

Creating a new function (AWS CLI):

aws lambda create-function \
  --function-name my-function \
  --runtime python3.13 \
  --role arn:aws:iam::123456789012:role/my-lambda-role \
  --handler app.handler \
  --code S3Bucket=amzn-s3-demo-bucket,S3Key=deployments/my-function.zip,S3ObjectVersion=abc123,S3ObjectStorageMode=REFERENCE

Updating an existing function:

aws lambda update-function-code \
  --function-name my-function \
  --s3-bucket amzn-s3-demo-bucket \
  --s3-key deployments/my-function.zip \
  --s3-object-version def456 \
  --s3-object-storage-mode REFERENCE

AWS Identity and Access Management permissions required for self-managed code storage

AWS Identity and Access Management (IAM) permissions

Lambda needs permission to read the deployment package from your bucket. You can grant access through an S3 bucket policy.

S3 bucket policy

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "LambdaSelfManagedCodeAccess",
      "Effect": "Allow",
      "Principal": {
        "Service": "lambda.amazonaws.com"
      },
      "Action": [
        "s3:GetObject",
        "s3:GetObjectVersion"
      ],
      "Resource": "arn:aws:s3:::amzn-s3-demo-bucket/deployments/my-function.zip",
      "Condition": {
        "ArnLike": {
          "aws:SourceArn": "arn:aws:lambda:us-east-1:123456789012:function:my-function"
        }
      }
    }
  ]
}

We recommend including the aws:SourceArn condition key scoped to your specific function ARN to allow for least-privileged access. Note the Resource is scoped to the exact S3 key rather than a wildcard prefix. This follows least-privilege and matches how the aws:SourceArn condition locks down which function can access which object.

Bucket requirements

Your S3 bucket must meet the following requirements:

  • Versioning (required). You must enable S3 versioning to make sure that Lambda references a specific, immutable artifact and to protect against accidental overwrites.
  • Encryption. The following encryption types are supported: SSE-S3, SSE-KMS (including customer-managed KMS keys), and DSSE-KMS. If you use SSE-KMS, the Lambda principal must have kms:Decrypt permission on the key.
  • Object Lock. Supported. You can apply Object Lock in Compliance or Governance mode to prevent accidental deletion of deployment artifacts.
  • Access logging. You can enable S3 server access logging or AWS CloudTrail data events to audit every time Lambda reads your code.

What happens when the object is unavailable

Lambda periodically accesses the source object from your S3 bucket to reoptimize your function code. You must maintain access to the source object for your function to remain active.

If Lambda loses access to the source object for a function, the function transitions to the Inactive state. To restore the function, restore access to the source object and then update the function.

Performance considerations

Lambda functions with self-managed code storage behave the same as standard Lambda functions with one difference during function creation and update. Lambda does not copy your deployment package to a Lambda-managed S3 bucket. In our testing with a 200MB Python 3.13 function, functions using self-managed storage showed function creation times approximately 5s less than the default COPY mode. Reading directly from your S3 bucket without an intermediate copy step can provide a modest advantage, particularly for larger deployment packages.

Getting started with infrastructure as code

Self-managed code storage can be implemented using infrastructure-as-code tooling with either the AWS CLI or AWS CloudFormation today.

AWS CLI

aws lambda create-function \
  --function-name my-function \
  --runtime python3.13 \
  --role arn:aws:iam::123456789012:role/my-lambda-role \
  --handler app.handler \
  --code S3Bucket=amzn-s3-demo-bucket,S3Key=deployments/my-function.zip,S3ObjectVersion=abc123,S3ObjectStorageMode=REFERENCE \
  --region us-east-1

AWS CloudFormation

MyFunction:
  Type: AWS::Lambda::Function
  Properties:
    FunctionName: my-function
    Runtime: python3.13
    Handler: app.handler
    Role: !GetAtt MyLambdaRole.Arn
    Code:
      S3Bucket: amzn-s3-demo-bucket
      S3Key: deployments/my-function.zip
      S3ObjectVersion: abc123
      S3ObjectStorageMode: REFERENCE

Using it at scale

Once you adopt self-managed S3 buckets for your Lambda deployment packages, your artifact bucket grows over time as you deploy new versions of your functions. This section covers strategies for managing that growth efficiently, keeping your versions organized, and planning for cross-Region deployments.

Managing artifact lifecycle with S3 lifecycle policies

Every time you update a function’s code, S3 creates a new object version in your bucket. The previous objects don’t disappear. They accumulate. Without a cleanup strategy, your storage grows indefinitely and old artifacts clutter your bucket.

S3 Lifecycle policies let you automate this entirely. You define rules that transition or delete objects based on age, and S3 executes them on your behalf: no scripts, no cron jobs, no manual intervention.

Strategy 1: Archive old versions to Glacier

If compliance or audit requirements mandate that you retain all historical deployment packages, but you rarely need to access them, transition old object versions to a lower-cost storage class:

{
  "Rules": [
    {
      "ID": "ArchiveOldDeploymentPackages",
      "Status": "Enabled",
      "Filter": {
        "Prefix": "deployments/"
      },
      "NoncurrentVersionTransitions": [
        {
          "NoncurrentDays": 30,
          "StorageClass": "GLACIER_FLEXIBLE_RETRIEVAL"
        }
      ]
    }
  ]
}

This rule transitions any non-current object version to S3 Glacier Flexible Retrieval after 30 days. Your active deployment packages remain in S3 Standard for fast access, while historical versions move to archival storage at a fraction of the cost.

For artifacts you need to retain for years but will rarely access again, consider a tiered approach: moving to Glacier Flexible Retrieval first, then to Deep Archive:

"NoncurrentVersionTransitions": [
  {
    "NoncurrentDays": 30,
    "StorageClass": "GLACIER_FLEXIBLE_RETRIEVAL"
  },
  {
    "NoncurrentDays": 365,
    "StorageClass": "DEEP_ARCHIVE"
  }
]

Strategy 2: Delete old versions you no longer need

If you don’t have a compliance requirement to retain every historical artifact, you can expire old versions outright:

{
  "Rules": [
    {
      "ID": "DeleteOldDeploymentPackages",
      "Status": "Enabled",
      "Filter": {
        "Prefix": "deployments/"
      },
      "NoncurrentVersionExpiration": {
        "NoncurrentDays": 14,
        "NewerNoncurrentVersions": 2
      }
    }
  ]
}

This rule keeps the 2 most recent non-current versions of each object (giving you a rollback path) and deletes anything older than 14 days beyond that. This aligns well with a deployment strategy where you want the ability to quickly roll back to your previous one or two releases, but don’t need to retain anything older.

Diagram showing the relationship between S3 object versions and Lambda function versions

Tracking object and function versions

With REFERENCE mode, there is a direct relationship between your S3 object version and your Lambda function version. We recommend the following practices:

  • Tag your objects with metadata from your CI/CD pipeline (commit SHA, build ID, pipeline run ID) so you can trace any deployed function back to the exact source that produced it.
  • Document the mapping between Lambda function versions (or aliases) and S3 object version IDs. This makes rollbacks straightforward: update the function to reference the previous object version.

Cross-account considerations

How you organize your artifact buckets across AWS accounts depends on your operational model:

  • Centralized artifact account: A single bucket in a shared-services or tooling account, with bucket policies granting cross-account s3:GetObject access to Lambda execution roles in workload accounts. This gives your platform team a single inventory of all deployment artifacts with consistent lifecycle, encryption, and access policies.
  • Per-account buckets: Each workload account owns its own artifact bucket. Requires less effort to set up, but harder to enforce consistent governance across many accounts.

Either pattern works with self-managed storage. Choose based on how your organization balances centralized control against team autonomy.

Cross-Region considerations

With REFERENCE mode, your S3 object is the authoritative copy for your function. Self-managed code storage supports cross-Region function creation within a partition for all default Regions (non-opt-in Regions). You can store your code packages in one Region and deploy your functions in another. This makes cross-Region planning critical. There are four factors to balance:

Disaster recovery

This is the most critical consideration. Because your S3 object is the single source of truth in REFERENCE mode, you do not want all your deployment artifacts in a single Region with no fallback. A recommended pattern:

  1. Primary Region: Your main artifact bucket where CI/CD pipelines deposit new deployment packages.
  2. Fallback Region: A secondary bucket populated via S3 Cross-Region Replication (CRR). If your primary Region becomes unavailable, you can update your Lambda functions to reference the replicated objects in the fallback Region.

Enable S3 Replication Time Control (RTC) if you need a guaranteed SLA (15 minutes) for replication completion.

Cost

Weigh replication + storage costs against per-deploy cross-Region data transfer. If you deploy frequently, storing replicated copies in each target Region is usually cheaper. For infrequent deployments, a one-time transfer may suffice.

Governance and data residency

Some organizations, particularly in regulated industries, have strict requirements about where code artifacts can reside. Before configuring cross-Region replication, confirm that your data is permitted to leave its current Region. Certain regulatory frameworks (for example, data sovereignty laws, FedRAMP boundaries) may restrict replication to specific Region pairs.

Performance

If your workload requires fast function creation and activation times, for example, in a CI/CD pipeline where deployment speed is critical, keep your S3 objects in the same Region where you are creating your Lambda functions. Cross-Region reads add latency to the initial code download, which directly impacts how quickly a new function version becomes active after deployment.

For workloads where creation speed is less critical (for example, batch processing functions that are updated infrequently), the latency of a cross-Region read might be acceptable and can simplify your architecture.

Things to know

Before adopting self-managed S3 buckets for your Lambda functions, keep the following in mind:

  • Availability: You can use this feature today in all AWS standard regions where Lambda is supported.
  • Pricing: There is no additional Lambda charge. You pay standard S3 costs for storage, and any cross-Region data transfer.
  • Maximum deployment package size: The existing limits apply: 250 MB unzipped.
  • Supported runtimes: All Lambda runtimes that support .zip deployment packages are compatible. Container image deployments are not affected by this feature.
  • Migration: You can switch an existing function from service-managed to self-managed storage by calling UpdateFunctionCode with the --s3-object-storage-mode REFERENCE parameter. Lambda recreates the function by referencing the object in your S3 bucket and deletes the saved copy.
  • Reverting: You can switch back to service-managed storage at any time by updating the function with --s3-object-storage-mode COPY. Lambda resumes copying the artifact to its internal bucket.
  • Object availability is your responsibility: In REFERENCE mode, Lambda depends on your S3 object being accessible. If the object is deleted, the bucket policy changes, or the KMS key is disabled, new invocations requiring a cold start will fail.

Conclusion

In this post, we showed how self-managed S3 buckets for Lambda give you more capacity, more control, and simpler compliance, all without changing how you write or invoke your functions. Your deployment packages no longer count against account quotas, your security team can apply the same policies to code artifacts that they apply everywhere else, and your disaster recovery story is as strong as the replication capabilities of S3.

To get started:

Unlocking the future of video data: March Networks cloud storage on AWS

Post Syndicated from Mehran Najafi original https://aws.amazon.com/blogs/architecture/unlocking-the-future-of-video-data-march-networks-cloud-storage-on-aws/

Enterprise video surveillance is operating at an unprecedented scale as organizations across retail, banking, quick-service restaurants (QSR), convenience stores, and transportation networks generate petabytes of video data across thousands of distributed locations. As retention requirements grow and organizations seek to extract more operational insights from video, traditional on-premise storage models are becoming increasingly difficult and expensive to scale.

March Networks is a global provider of intelligent video surveillance and business intelligence solutions serving enterprises across banking, retail, quick-service restaurants, transportation, and other multi-site environments. With more than 25 years of experience in video technology, the company helps organizations transform video data into operational insights through cloud-based platforms, AI-powered analytics, and enterprise-scale video management.

Unlocking the power of video data

In this post, we show how March Networks built a scalable cloud architecture on Amazon Web Services (AWS) to support large-scale enterprise video storage and analytics. The solution uses Amazon Simple Storage Service (Amazon S3) and Amazon S3 Glacier to manage long-term video retention, while integrating with additional AWS services to support ingestion, lifecycle management, monitoring, and secure access. We also explore how this architecture enables advanced video analytics using technologies such as Amazon S3 Vectors and Amazon Bedrock, helping organizations store petabyte-scale video data more cost-effectively while accelerating investigations and operational insights.

The challenge: Managing enterprise video at scale

Historically, enterprise video has been stored on local network video recorders (NVRs) and on-premise servers deployed at each site. Although this model provides localized control, it creates fragmented storage environments that require frequent hardware expansion, ongoing maintenance, and inconsistent retention policies across locations. This also limits organizations’ ability to centrally access, analyze, and govern video data across their enterprise.

As organizations increase video retention periods for compliance, liability protection, and operational intelligence, infrastructure requirements grow rapidly. Adding local storage hardware across hundreds or thousands of sites increases operational complexity and introduces lifecycle management challenges.

The economic impact of cloud video storage

Cloud storage introduces a more flexible model by consolidating distributed video data into centralized, elastic storage infrastructure. Even partial migration (such as moving long-term retention or compliance archives to the cloud), can significantly reduce infrastructure overhead while enabling centralized data management and analytics.

The financial impact of this shift can be substantial. For example, one retail organization evaluated the benefit of moving to a hybrid cloud storage model to extend video retention for a period of up to 5 years — a common retention window driven by compliance standards and laws — without adding new on-premise hardware. This customer operated more than 580 cameras, generating approximately 5,600 TB of archived video. The total storage required depends on factors such as video bitrate and quality, camera count, and backup duration. Their estimated cloud storage cost using a third-party cloud provider was approximately $347,000 per year, compared to roughly $1.7 million annually to store the same volume of video on-premise. For long-term cloud storage, data is not expired or deleted; customers are notified as their storage quota approaches capacity and can purchase additional storage as needed. By retaining recent footage locally while archiving older video to a third-party cloud provider, the organization significantly reduced storage costs while maintaining access to archived footage when needed.

Solution overview: March Networks cloud storage on AWS

March Networks Cloud Storage is a cloud-based video storage solution built on AWS. It is designed for distributed enterprise environments such as retail chains, financial institutions, convenience stores, and transportation systems that operate thousands of cameras across geographically dispersed locations.

The solution leverages Amazon S3 and Amazon S3 Glacier to provide scalable and durable storage for large volumes of video data while integrating AWS services that support secure ingestion, lifecycle management, monitoring, and access control. By combining AWS cloud infrastructure with March Networks’ video surveillance expertise, organizations can modernize video retention strategies while maintaining operational flexibility.

The platform supports multiple deployment models that allow organizations to adopt cloud storage at their own pace. Hybrid architectures allow recent footage to remain on-site for immediate access while older video is archived to the cloud. In other deployments, organizations can move a majority of video storage into AWS to reduce on-premise infrastructure and simplify long-term retention management.

Because the platform is built on AWS, storage capacity scales automatically as organizations add cameras, extend retention periods, or onboard new sites. This allows customers to grow video storage environments without hardware planning, or infrastructure expansion.

Architecture deep dive

The Cloud Storage architecture integrates on-premise video infrastructure with AWS services that manage ingestion, storage, monitoring, and secure access to video data.

At a high level, the architecture connects local video systems, including NVRs, cameras, and client applications, to AWS cloud services through secure network connections. March Networks securely ingests video data into AWS storage infrastructure, where customers can retain, monitor, and retrieve it based on their defined policies.

Figure 1: March Networks Architecture on AWS.

Video ingestion and storage

March Networks securely uploads video recorded on local NVRs to Amazon S3 buckets using encrypted transmission protocols. Amazon S3 provides highly durable object storage designed to store large volumes of data while enabling efficient retrieval and lifecycle management.

Once stored, organizations can retain video data for active investigations or operational review. Organizations configure lifecycle management policies that automatically move older footage to lower-cost storage tiers based on their access patterns.

Tiered storage with Amazon S3 and Amazon S3 Glacier

Video storage requirements vary depending on how frequently footage must be accessed. The platform uses multiple Amazon S3 tiers to align performance and cost with real-world video access patterns.

Amazon S3 Standard and Amazon S3 Standard-Infrequent Access (S3 Standard-IA) support video that must remain readily accessible for investigations, operational review, or analytics. For long-term retention, the platform uses Amazon S3 Glacier storage tiers to provide ultra-low-cost archival storage for footage that must be preserved but is rarely accessed.

Lifecycle policies automatically transition videos between tiers according to customer-defined retention policies. This allows organizations to store high-value recent video on high-performance storage while archiving older footage economically.

Supporting AWS services

Several AWS services support the reliability, scalability, and operational visibility of the platform:

  • Amazon Simple Queue Service (Amazon SQS) manages asynchronous messaging between system components, enabling reliable communication between ingestion, processing, and storage services.
  • Amazon Simple Email Service (Amazon SES) provides notification capabilities for operational alerts and system events.
  • Amazon CloudWatch monitors system performance, logs activity, and provides operational visibility into cloud infrastructure.
  • AWS Security Token Service (AWS STS) enables secure authentication and temporary credentials for system components accessing cloud resources.

For metadata management and caching, the platform uses PostgreSQL and Amazon ElastiCache for Redis to maintain high-performance access to video metadata and system state.

Together, these services enable March Networks to deliver a secure, scalable cloud architecture capable of supporting petabyte-scale video workloads across distributed environments.

Outcomes and benefits

By building its video storage architecture on AWS, March Networks enables organizations to modernize video infrastructure while reducing operational complexity and long-term storage costs. This includes:

Reduced storage costs

Tiered storage using Amazon S3 and Amazon S3 Glacier allows organizations to align storage costs with actual video access patterns. Frequently accessed footage remains readily available, while older video can be archived at significantly lower cost.

Elastic scalability

AWS infrastructure enables organizations to scale video storage across hundreds or thousands of locations without adding on-premise hardware. As organizations add cameras or extend retention periods, storage capacity expands automatically.

Centralized investigations and governance

Cloud-based video storage enables security and operations teams to investigate incidents across multiple sites using a centralized platform. Organizations can apply consistent retention policies, maintain audit trails, and enforce standardized governance across all locations.

Centralized video storage also enables advanced analytics capabilities. March Networks integrates AI-powered tools such as AI Smart Search, which allows users to locate relevant footage using natural-language queries across large video archives.

These capabilities leverage technologies, including Amazon S3 Vectors and Amazon Bedrock to support semantic search and AI-driven video intelligence across enterprise-scale datasets.

Conclusion

As organizations generate increasing volumes of video data, scalable cloud infrastructure becomes essential for managing long-term storage and enabling advanced analytics. By building its Cloud Storage platform on AWS, March Networks provides organizations with a durable, secure, and cost-efficient foundation for enterprise video retention.

Services such as Amazon S3, Amazon S3 Glacier, Amazon SQS, Amazon CloudWatch, and AWS Security Token Service support a scalable architecture capable of storing and managing petabytes of video data across distributed environments. This cloud-native approach allows organizations to modernize video infrastructure today while preparing for future AI-driven analytics and operational intelligence.

Learn more about how March Networks Cloud Storage powered by AWS services can modernize your video infrastructure.


About the authors

Specification-driven composition for flexible data workflows

Post Syndicated from Rostislav Markov original https://aws.amazon.com/blogs/architecture/specification-driven-composition-for-flexible-data-workflows/

Specification-driven composition addresses a common scalability bottleneck in data pipelines. Data pipelines often start as simple scripts, but as they grow, you duplicate transformation logic and small changes cascade across multiple workflows. Copying and modifying data transformation logic across scripts leads to workflows that become difficult to manage at scale. Tracking what each pipeline does becomes harder because workflow intent is embedded in code. This lack of visibility complicates governance, especially in regulated environments such as healthcare, finance, and life sciences.

Many implementations combine orchestration, transformation logic, and validation rules in the same scripts. Supporting new datasets requires modifying and redeploying code, while validation often happens only during processing. As a result, issues surface late in the lifecycle which increases the operational risk. Specification-driven composition separates workflow intent from implementation so you can build flexible data workflows.

In this post, I show how to apply specification-driven composition to data transformation workflows. I explain the challenges with script-based pipelines, introduce the pattern and its core components, and walk through a serverless implementation using AWS Lambda, AWS Step Functions, Amazon Simple Storage Service (Amazon S3), and Amazon OpenSearch Service.

Solution overview

You can separate workflow intent from processing logic with specification-driven composition. This approach reduces duplication, shortens the time required to onboard new datasets, and improves consistency across workflows. Instead of embedding logic in scripts, the system describes workflow intent in a structured specification, validates the specification before processing, and dynamically assembles a processing pipeline.

This approach moves pipeline configuration outside application code and composes pipelines from reusable processing components. To separate concerns, it organizes a workflow into three layers, as shown in Figure 1. The intent layer defines workflow behavior using specifications. The composition layer validates specifications and assembles pipelines. The processing layer runs the pipeline of transformation steps.

A diagram showing the three layers of specification-driven composition. The intent layer holds the specification, the composition layer contains the composer and capability registry, and the processing layer runs the capability pipeline.

Figure 1. Specification-Driven Composition design pattern.

Benefits

Specification-driven composition provides several practical benefits when you manage multiple pipelines. First, it improves governance because specifications provide a clear, traceable description of workflow behavior that you can review and validate before invocation. In regulated industries, this traceability shortens audit preparation time and reduces the review burden for new dataset submissions.

Second, the pattern supports reusable transformations. You implement transformation logic once and reuse it across multiple workflows. This reduces duplication and improves consistency. In practice, teams adopting this pattern report being able to onboard new datasets in days rather than weeks because most required capabilities already exist in the registry.

Third, specification-driven composition enables flexible pipeline design. You define new specifications to create pipelines supporting new datasets and use cases without modifying application code and registering new system release.

Fourth, the pattern separates business intent from execution artifacts. The specification expresses what the workflow should do in domain terms, while the generated state machine remains a system artifact. This separation matters in regulated environments (for example, GxP) where business users author intent but are not allowed to author or modify execution code directly.

Finally, the declarative representation of workflows lets AI tools assist with capability discovery, specification authoring, and pipeline analysis, while runtime behavior stays predictable as it relies on validated capabilities.

Core components

You work with four key components to define, validate, and run workflows.

  1. Specification

A specification is a structured document, typically JSON or YAML, that describes datasets, mappings, and transformations. It defines what the workflow should do without including processing logic. Because specifications are explicit and versioned, they provide a clear record of workflow intent.

  1. Composer

The composer converts specifications into runnable steps, so workflows run consistently without embedding transformation logic in application code. It checks that referenced capabilities exist, retrieves metadata, and builds a workflow that can run on the processing layer. The composer does not perform transformations. It only assembles the workflow. In practice, the composer compiles business intent expressed in the specification into a code artifact such as an Amazon States Language (ASL) definition. This abstraction lets domain users author specifications without producing runnable code, which is important in environments with strict separation of duties.

  1. Capability registry

The registry stores metadata about reusable transformation functions. This includes identifiers, input/output formats, invocation details, and permission boundaries. The composer uses the registry to validate specifications and locate capabilities. Treat this registry as a governed artifact rather than a manually edited lookup table. Capability definitions live in version control, and your CI/CD pipeline validates metadata and runs tests before you publish new versions. Specification authors include explicit capability version references in the specifications to support reproducible workflow runs. In regulated systems, you must validate new capabilities and obtain approval through a separate workflow before you register them.

  1. Capability pipeline

Once assembled, the pipeline runs a sequence of transformation steps. Each step performs a specific operation such as formatting, validation, or enrichment. Because these steps are reusable, you can apply them across many workflows.

Technical implementation

Let’s walk through a technical implementation of this pattern using serverless AWS services. In this example, workflow specifications are uploaded to an S3 bucket. An AWS Lambda composer retrieves and validates the specification, looking up capability metadata in Amazon OpenSearch Service. The composer then assembles the workflow in AWS Step Functions, which orchestrates the workflow and invokes AWS Lambda capability processors. Each processor emits traces to Amazon CloudWatch Logs.

Figure 2 shows the architecture.

Users upload specifications to Amazon S3, which invokes the Lambda composer. The composer queries the OpenSearch registry and assembles a Step Functions workflow of Lambda capability processors, which emit traces to CloudWatch.

Figure 2. AWS implementation of Specification-Driven Composition

Interpreting the workflow specification

The workflow specification defines datasets and transformation logic using a structured format (in this example, JSON). A specification is a declarative document that describes what the pipeline should produce rather than how to produce it. Your composer reads the specification, validates it against a schema, and uses it to construct the pipeline.

The following example maps source fields to target fields using reusable capabilities (Figure 3). It takes data from a source dataset (‘raw_orders’), maps specific fields (‘order_date’, ‘amount’) and applies reusable transformation capabilities such as ‘format_date’ and ‘normalize_currency’. Each mapping explicitly links a source field to a target field and references a capability that performs the transformation. Source dataset(s) are listed under the ‘source’ section of the JSON document, target datasets under the ‘target’ section, and mappings ‘mappings’. You can define your own specification structure and build custom validation logic in your composer to make sure specifications are valid.

{
  "source": {
    "dataset": "raw_orders"
  },
  "target": {
    "dataset": "orders_clean"
  },
  "mappings": [
    {
      "source_field": "order_date",
      "target_field": "order_date",
      "transformation": {
        "capability": "format_date"
      }
    },
    {
      "source_field": "amount",
      "target_field": "amount_normalized",
      "transformation": {
        "capability": "normalize_currency"
      }
    }
  ]
}

You can model preprocessing steps such as column standardization, numeric casting, or unit conversion as first-class capabilities and reference them earlier in the specification (for example, in a dedicated ‘preprocessing’ section) before downstream mappings run. This way, preparation logic uses the same metadata, versioning, validation, and observability model as the rest of the workflow, which simplifies lineage and review.

In this example, an S3 event notification invokes the composer Lambda function when you upload a specification. In practice, the same composer can be invoked through several mechanisms depending on the use case: S3 events for new specifications, an Amazon EventBridge schedule for recurring runs, an API or UI action for on-demand invocation, a direct Step Functions StartExecution call, or an upstream pipeline. This flexibility lets you re-run an approved specification against refreshed data without re-authoring or re-approving the workflow.

The composer parses the specification and validates the referenced capabilities by querying Amazon OpenSearch Service to retrieve capability metadata such as Amazon Resource Names (ARNs). OpenSearch Service is used here because the composer does more than direct-key lookups. It supports capability discovery through full-text and semantic search over capability metadata such as capability descriptions, input/output schemas, and tags. This lets data authors and AI tools find reusable capabilities by intent rather than by exact identifier. After validation, the composer assembles and starts an AWS Step Functions state machine which invokes each capability in sequence. Each capability runs independently, making the pipeline modular and reusable.

Securing sensitive data flows

This pattern suits regulated workloads, so handle security as part of the design. Use SSE-KMS with a customer managed key on the specification and data S3 buckets and enable encryption at rest on the Amazon OpenSearch Service domain. Enforce HTTPS (TLS) access with an S3 bucket policy (aws:SecureTransport) and enable node-to-node encryption on Amazon OpenSearch Service. AWS Step Functions and Lambda calls use TLS by default. Each capability processor receives only the fields its mapping references, and you can apply IAM policy at the source bucket to restrict access. Processors emit traces to Amazon CloudWatch Logs.

For data classification, you can tag sensitive fields in the specification (example: "sensitivity": "PHI") and declare the sensitivity of each capability in the registry: a direct-move capability preserves the source classification, a date-of-birth-to-age capability clears it, and an enrichment that introduces sensitive data sets it. The composer combines the source tag with the capability’s behavior to derive the target field’s sensitivity, validating that the combination resolves clearly before assembling the pipeline. It then generates the masking artifact for the output (for example, AWS Lake Formation column grants) so consumers get correct masking without a separate masking specification or manual effort.

Recognizing the pattern

This approach works well when you describe workflows using structured specifications, reuse transformation logic across pipelines, require validation before invocation, and require workflows to be deterministic and auditable. You are likely to recognize the pattern in regulated data pipelines for the submission of tabular datasets to oversight agencies.

Consider clinical trial reporting as a concrete example. Data analysts collect raw data from clinical sites and must transform it into a standard submission format such as the Study Data Tabulation Model (SDTM) before submission to agencies such as the US Food and Drug Administration. With specification-driven composition, data analysts define specifications that map collected data about adverse events, demographics, and vital signs to the standard target variables, and the validated output feeds downstream systems such as patient safety and medical monitoring.

That said, this pattern might add unnecessary complexity for simple, one-time data transformations or pipelines with fewer than three to five workflows. Evaluate this pattern’s impact by tracking the reduction in duplicated transformation logic across pipelines, the time required to onboard new datasets, and the number of workflows you can create without modifying application code.

Conclusion

Script-based data pipelines accumulate hidden costs as they grow, including duplicated logic across files and late-breaking validation failures. Specification-driven composition separates workflow intent from processing so you can manage data workflows more consistently at scale. The result is faster dataset onboarding, stronger governance, and pipelines that are transparent enough to trust in regulated environments.

This pattern is especially valuable for regulated reporting pipelines, multi-source data integration, and reusable ETL frameworks where traceability and flexibility matter. By investing a small set of reusable capabilities and a disciplined specification format, you can reduce the engineering effort for new pipelines by treating them more as configuration tasks which may be delegated to system users.

Next steps

To get started, take one existing pipeline and describe it as a specification. Implement a small set of reusable transformation functions and use them to assemble your first composed workflow. The AWS Lambda event-driven architectures guide is a good starting point for wiring S3 uploads to your composer, and the AWS Step Functions and Lambda integration guide will help you orchestrate your capability processors. To monitor the pipeline, see publishing custom CloudWatch metrics.

For a practical first use case, try applying the pattern to a reporting pipeline you maintain today that has three or more variants such as monthly finance reports generated from different source systems. Replace the duplicated scripts with a single composer and a shared capability library, and measure the onboarding time for the next variant. As you expand your capability library, you can apply the same pattern across additional workflows and standardize how transformations are defined and run.


About the author

Modernizing Lambda + S3 workloads with Amazon S3 Files

Post Syndicated from Sahithi Ginjupalli original https://aws.amazon.com/blogs/compute/modernizing-lambda-s3-workloads-with-amazon-s3-files/

Learn how Amazon S3 Files simplifies Lambda functions by eliminating transfer code and /tmp constraints. See three modernization patterns with code examples for image processing, ETL pipelines, and multi-agent AI workloads.

AWS Lambda functions that interact with Amazon Simple Storage Service (Amazon S3) typically follow a familiar pattern: download an object to /tmp, process it locally, and upload the result back to S3. This pattern is well-understood and reliable, but it requires you to write code for managing transfers, monitoring /tmp capacity, and cleaning up ephemeral storage alongside your actual processing logic.

Amazon S3 Files changes this by letting your Lambda function mount an S3 bucket as a file system. Your function reads and writes files at a local mount path (such as /mnt/data), and the file system handles synchronization with S3 automatically. The transfer and storage management code goes away, and what remains is your processing logic working directly with files.

In this post, we walk through three common Lambda + S3 workloads and show how to modernize each one by using S3 Files. You will see how the code gets shorter, the /tmp size constraint disappears, and the developer experience improves.

Walkthrough

Prerequisites

Before you begin, make sure you have:

  • An AWS account with permissions to create Lambda functions, S3 file systems, and VPC resources.
  • An existing VPC with private subnets and appropriate security groups.

Getting started

To integrate a Lambda function with S3 Files, you can follow these three steps:

  1. Create an S3 file system for your bucket. You can do this through the S3 console, AWS Command Line Interface (AWS CLI), or AWS CloudFormation. This single operation creates the file system, mount targets in your Amazon Virtual Private Cloud (Amazon VPC), and an access point.
  2. Add the file system configuration to your Lambda function. Specify the access point ARN and local mount path (for example, /mnt/data). Your function must be in a VPC with access to the mount target. For optimal throughput on large files, configure your function with 512 MB or more of memory to enable direct reads from S3.
  3. If you are modernizing your existing Lambda function’s code, replace boto3 transfer code with file paths. Change s3.download_file(bucket, key, '/tmp/file') to open('/mnt/data/' + key) and remove upload and cleanup logic.

Your function’s execution role needs s3files:ClientMount and s3files:ClientWrite permissions (included in the AmazonS3FilesClientReadWriteAccess managed policy). For direct S3 reads on large files, also add s3:GetObject and s3:GetObjectVersion.

Pattern 1: Multi-agent shared workspace

Agentic AI workloads, where multiple autonomous agents collaborate on a task, require shared mutable state. Agents need to read each other’s outputs, write intermediate artifacts, and coordinate without tight coupling. With Lambda today, this typically means serializing state to S3 objects or Amazon DynamoDB between every step, adding latency and code for each handoff.

S3 Files gives multiple Lambda functions a shared file system. Agents communicate through the file system itself, with no S3 API calls and no serialization overhead.

Example: Collaborative research agents

Three Lambda functions mount the same S3 bucket at /mnt/workspace. An orchestrator prepares the task, research agents work in parallel, and a synthesis agent combines their findings:

import os
import json

WORKSPACE = "/mnt/workspace"

# --- Orchestrator Agent ---
def orchestrator_handler(event, context):
    session_id = event["session_id"]
    session_dir = f"{WORKSPACE}/sessions/{session_id}"

    os.makedirs(f"{session_dir}/research", exist_ok=True)
    os.makedirs(f"{session_dir}/output", exist_ok=True)

    # Write task assignments directly to shared workspace
    with open(f"{session_dir}/manifest.json", "w") as f:
        json.dump({
            "query": event["research_query"],
            "agents": ["market_analysis", "technical_review", "competitor_scan"],
            "status": "in_progress"
        }, f)

    return {"session_dir": session_dir}


# --- Research Agent (one of many, running in parallel) ---
def research_agent_handler(event, context):
    session_dir = event["session_dir"]
    agent_name = event["agent_name"]

    # Read task from shared workspace (no S3 GET call)
    manifest = json.load(open(f"{session_dir}/manifest.json"))

    # Perform research (invoke Amazon Bedrock, search, etc.)
    # TODO: Implement perform_research() for your use case
    findings = perform_research(manifest["query"], agent_name)

    # Write results to shared workspace (no S3 PUT call)
    with open(f"{session_dir}/research/{agent_name}.json", "w") as f:
        json.dump(findings, f, indent=2)

    return {"status": "complete", "agent": agent_name}


# --- Synthesis Agent ---
def synthesis_handler(event, context):
    session_dir = event["session_dir"]

    # Read all research outputs from shared directory
    all_findings = {}
    for f in os.listdir(f"{session_dir}/research"):
        with open(f"{session_dir}/research/{f}") as fh:
            all_findings[f.replace(".json", "")] = json.load(fh)

    # Synthesize and write final report
    # TODO: Implement synthesize_findings() for your use case
    report = synthesize_findings(all_findings)
    with open(f"{session_dir}/output/report.md", "w") as f:
        f.write(report)

    return {"report_path": f"{session_dir}/output/report.md"}

In the traditional approach, each agent would need to call s3.get_object() to read the manifest, s3.put_object() to write findings, and the synthesis agent would need to call s3.list_objects() then s3.get_object() for each result. That’s eight or more S3 API calls per workflow run replaced by file I/O.

What the shared workspace pattern gives you:

  • Agents discover each other’s outputs by listing a directory (no coordination logic needed).
  • Sessions, agents, and outputs map to directories, not flat object key conventions.
  • Close-to-open consistency means that when an agent closes a file after writing, the next agent to open it sees the complete content.
  • No need to marshal state into S3 PutObject calls between steps.

Pattern 2: Image thumbnail generation

The S3 thumbnail generator is a common Lambda + S3 pattern. An image is uploaded to S3, a Lambda function is triggered, it downloads the image, resizes it with Pillow, and uploads the thumbnail to a destination bucket.

The traditional approach

import boto3
import os
import uuid
from urllib.parse import unquote_plus
from PIL import Image

s3_client = boto3.client('s3')

def resize_image(image_path, resized_path):
    with Image.open(image_path) as image:
        image.thumbnail(tuple(x / 2 for x in image.size))
        image.save(resized_path)

def handler(event, context):
    for record in event['Records']:
        bucket = record['s3']['bucket']['name']
        key = unquote_plus(record['s3']['object']['key'])
        tmpkey = key.replace('/', '')
        download_path = '/tmp/{}{}'.format(uuid.uuid4(), tmpkey)
        upload_path = '/tmp/resized-{}'.format(tmpkey)

        s3_client.download_file(bucket, key, download_path)
        resize_image(download_path, upload_path)
        s3_client.upload_file(
            upload_path, '{}-resized'.format(bucket), 'resized-{}'.format(key)
        )

What this approach requires you to manage beyond the core resize logic:

  • Transfer orchestration: Downloading the source, uploading the result, and handling partial transfer failures.
  • Storage capacity: Both the source and resized image must fit in /tmp simultaneously.
  • Ephemeral storage cleanup: If the function fails mid-execution or is reused across invocations, orphaned files can accumulate in /tmp.
  • Redundant downloads: If the same image triggers a retry, it must be downloaded again.

With the file system approach

import os
from urllib.parse import unquote_plus
from PIL import Image

MOUNT = "/mnt/images"

def resize_image(image_path, resized_path):
    with Image.open(image_path) as image:
        image.thumbnail(tuple(x / 2 for x in image.size))
        image.save(resized_path)

def handler(event, context):
    for record in event['Records']:
        key = unquote_plus(record['s3']['object']['key'])
        input_path = f"{MOUNT}/source/{key}"
        output_path = f"{MOUNT}/resized/resized-{os.path.basename(key)}"

        os.makedirs(os.path.dirname(output_path), exist_ok=True)
        resize_image(input_path, output_path)

What changed

The function moves from a download-process-upload pipeline to direct file I/O. No boto3 client, no /tmp management, no upload step. The resize_image function is unchanged because it always worked with file paths. The difference is that those paths now point to a mounted S3 file system instead of ephemeral local storage.

You still handle errors in your processing logic (for example, invalid image formats). What you no longer need to handle are transfer-specific failure modes like partial downloads, failed uploads, or /tmp capacity checks.

Metric Traditional S3 Files
Lines of code (non-blank) 22 15
S3 API calls per invocation 2 (GET + PUT) 0
Max image size Source + output files share /tmp No /tmp constraint
boto3 dependency Required Not needed

Pattern 3: CSV-to-Parquet ETL pipeline

Another commonly used serverless ETL pattern is an S3 event triggers a Lambda function when CSV files land in a bucket. The function downloads the CSV, transforms it to Parquet by using pandas and pyarrow, and uploads the result.

The traditional approach

import boto3
import pandas as pd
import os

s3 = boto3.client("s3")
BUCKET = "data-pipeline-bucket"

def handler(event, context):
    key = event["Records"][0]["s3"]["object"]["key"]
    filename = os.path.basename(key)
    local_input = f"/tmp/{filename}"
    local_output = f"/tmp/{filename.replace('.csv', '.parquet')}"

    try:
        # Download from S3
        s3.download_file(BUCKET, key, local_input)

        # Check /tmp space (10 GB limit)
        tmp_usage = sum(
            os.path.getsize(f"/tmp/{f}")
            for f in os.listdir("/tmp") if os.path.isfile(f"/tmp/{f}")
        )
        if tmp_usage > 9 * 1024**3:  # 9 GB safety margin
            raise RuntimeError("Approaching /tmp storage limit")

        # Transform
        df = pd.read_csv(local_input)
        df["processed_at"] = pd.Timestamp.now()
        df.to_parquet(local_output, engine="pyarrow", compression="snappy")

        # Upload result back to S3
        output_key = key.replace("raw/", "processed/").replace(".csv", ".parquet")
        s3.upload_file(local_output, BUCKET, output_key)

        return {"status": "success", "output_key": output_key}

    finally:
        # Clean up /tmp
        for f in [local_input, local_output]:
            if os.path.exists(f):
                os.remove(f)

What this approach requires you to manage beyond the core transform logic:

  • Storage capacity: Source and output files share /tmp, limiting practical file size.
  • Cold start cost: Initializing the boto3 client adds startup latency.
  • Transfer failure modes: Partial downloads, failed uploads, and orphaned /tmp files need their own handling.
  • Redundant downloads: Retries or reprocessing require downloading the same file again.

With the file system approach

import pandas as pd
import os

MOUNT = "/mnt/data"

def handler(event, context):
    key = event["Records"][0]["s3"]["object"]["key"]
    input_path = f"{MOUNT}/{key}"
    output_path = f"{MOUNT}/{key.replace('raw/', 'processed/').replace('.csv', '.parquet')}"

    # Ensure output directory exists
    os.makedirs(os.path.dirname(output_path), exist_ok=True)

    # Transform: direct file access, no download/upload
    df = pd.read_csv(input_path)
    df["processed_at"] = pd.Timestamp.now()
    df.to_parquet(output_path, engine="pyarrow", compression="snappy")

    return {"status": "success", "output_path": output_path}

What changed

With this change, a developer reading this code sees only the transform logic (read CSV, add column, write Parquet). The storage mechanics are handled by the file system.

Metric Traditional S3 Files
Lines of code (non-blank) 33 14
S3 API calls per invocation 2 (GET + PUT) 0
Max file size Source + output share /tmp No /tmp constraint
Cleanup logic required Yes No
/tmp space monitoring Yes No

Choosing the right approach: file system mounts vs. traditional access

Use case Recommendation
Lambda reads/writes files from S3 S3 Files (eliminates transfer boilerplate)
Multiple functions share data S3 Files (shared mount replaces API coordination)
Files > 10 GB S3 Files (no /tmp size constraint)
Event-driven processing (trigger on upload) S3 Files (S3 event triggers still work, function reads from mount)
Direct S3 API features (presigned URLs, S3 Select, multipart upload) Traditional (these require the S3 API)
Functions outside a VPC Traditional (S3 Files requires VPC connectivity)

Cleaning up

If you created resources while following along with this post, delete them to avoid incurring future costs. Start by removing the file system configuration from your Lambda function settings. Next, remove the S3 file system, which also deletes its associated mount targets and access points. Then delete the S3 buckets used for source and output data, along with the Lambda functions created for the examples. Finally, remove the IAM roles and policies created for Lambda execution or, if you added the S3 Files permissions (s3files:ClientMount, s3files:ClientWrite, s3:GetObject, s3:GetObjectVersion) to an existing role, remove these permissions. Additionally, If you created a new VPC for this tutorial, delete the VPC, which will also remove the associated private subnets, security groups, and route tables. If you used an existing VPC, remove the security groups and subnets created for this testing.

Warning: Deletion of an S3 bucket and its contents permanently deletes all objects in the buckets and cannot be undone. Make sure you have backed up any data you need to retain before proceeding.

Conclusion

In this post, we demonstrated how to modernize three common Lambda + S3 workloads by using Amazon S3 Files. Across image thumbnail generation, ETL pipelines, and multi-agent AI workloads, the migration follows the same principle: replace S3 API transfer logic with native file I/O and let the file system handle synchronization.

The improvements are consistent:

  • Less code: Transfer and cleanup logic goes away, leaving only your processing logic.
  • No /tmp size constraint: Process large files without local storage limits.
  • Zero S3 API calls for data access: Reads and writes go through the file system mount.
  • Fewer failure modes to handle: Transfer-specific issues (partial downloads, failed uploads, orphaned temp files) no longer apply.

For teams running Lambda + S3 workloads today, S3 Files isn’t a new architecture to learn. It’s transfer code you can remove. To learn more, see the S3 Files section in the Lambda documentation. To track upcoming features on the AWS Lambda roadmap, you can refer to the AWS Lambda roadmap.

Building Memory-Intensive Apps with AWS Lambda Managed Instances

Post Syndicated from Guy Haddad original https://aws.amazon.com/blogs/compute/building-memory-intensive-apps-with-aws-lambda-managed-instances/

Building memory-intensive applications with AWS Lambda just got easier. AWS Lambda Managed Instances gives you up to 32 GB of memory—3x more than standard AWS Lambda—while maintaining the serverless experience you know. Modern applications increasingly require substantial memory resources to process large datasets, perform complex analytics, and deliver real-time insights for use cases such as in-memory analytics, Machine Learning (ML) model inference, and real-time semantic search. AWS Lambda Managed Instances gives you a familiar serverless programming model and experience combined with the flexibility of being able to choose the underlying Amazon EC2 instance types and providing developers with access to large memory configurations.

In this post, you will see how AWS Lambda Managed Instances enables memory-intensive workloads that were previously challenging to run in serverless environments, using an AI-powered customer analytics application as a practical example. You’ll see cost savings of up to 33% compared to standard Lambda for predictable workloads, while eliminating the operational overhead of managing EC2 instances.

Understanding AWS Lambda Managed Instances

AWS Lambda Managed Instances runs your AWS Lambda functions on the Amazon EC2 instance types of your choice in your account, including Graviton4 and memory-optimized instance types. AWS handles underlying infrastructure lifecycle including provisioning, scaling, patching, and routing, while you benefit from Amazon EC2 pricing advantages like Savings Plans and Reserved Instances.

Key benefits include:

  • Flexible instance selection: Choose from compute-optimized (C), general-purpose (M), and memory-optimized (R) instance families
  • Configurable memory-CPU ratios: Optimize resource allocation for your workload
  • Multi-concurrent invocations: One execution environment handles multiple invocations simultaneously, improving utilization for I/O-heavy applications
  • Dynamic scaling: Instances scale based on CPU utilization without cold starts

AWS Lambda Managed Instances is best suited for high-volume, predictable workloads that benefit from sustained compute capacity and larger memory configurations.

Memory-Intensive Workloads Work Best with AWS Lambda Managed Instances

This blog focuses on one of AWS Lambda Managed Instances’ most powerful capabilities: running memory-intensive workloads that require more than the standard AWS Lambda’s 10 GB memory and 250MB ZIP limits. Here are the use cases where AWS Lambda Managed Instances helps:

  • In-Memory Analytics — Load gigabytes of structured data into memory at initialization and serve sub-millisecond analytical queries across thousands of invocations
  • ML Model Inference — Keep large model weights resident in memory across invocations for consistent, low-latency inference without a dedicated endpoint.
  • Real-Time Semantic Search — Build vector similarity search over large embedding indexes held entirely in memory, enabling natural language queries over millions of records without an external vector database.
  • Graph Processing — Hold large graph structures in memory for traversal algorithms that require the full graph to be accessible at once.
  • Scientific & Numerical Computing — Run simulations, Monte Carlo methods, and large matrix operations that require substantial working memory and benefit from memory-optimized Amazon EC2 instance families.
  • Large-Scale Report Generation — Aggregate and transform multi-gigabyte datasets in memory to generate complex reports or dashboards on demand, without staging data through intermediate storage.

Use Case: AI-Powered Customer Analytics with AWS Lambda Managed Instances

To demonstrate the power of AWS Lambda Managed Instances for memory-intensive applications, we built an AI-Powered Customer Analytics application that combines in-memory data processing with ML-based semantic search. The application loads in memory 1 million customer behavioral records (sessions, purchases, browsing patterns) from a Parquet file in S3 into a Pandas DataFrame and an embeddings cache consuming 200MB, then responds for analytics queries:

  1. Customer Analysis — Deep-dive into individual customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments
  2. Semantic Search — Natural language queries powered by FastEmbed (sentence-transformers/all-MiniLM-L6-v2) that find similar customers using vector similarity
  3. Cohort Analysis — Real-time segmentation by device, country, age group with aggregated metrics

Architecture Overview

Our AI-powered customer analytics application demonstrates this in practice: 1 million records in memory (200MB), a compact sentence transformer model for semantic search, sub-second query performance, and zero infrastructure to manage. The solution uses a simple, serverless architecture:

  • Customer transaction data (Parquet format) is stored in Amazon S3
  • Amazon Cognito User Pool authenticates users and issues JWT tokens for API access
  • Amazon API Gateway routes requests with Cognito authorizer validation, rate limiting (5 requests/second, burst 10), X-Ray tracing, and access logging
  • AWS Lambda function with AWS Lambda Managed Instances loads the entire dataset (200MB) and all-MiniLM-L6-v2 model (900MB) into memory during initialization while also performing a threaded embeddings cache generation. This step can consume about 14GB of the allocated memory, exceeding standard AWS Lambda’s 10 GB limit
  • Analytics queries execute against the in-memory data using the model
  • Results are returned in milliseconds for interactive analysis

Architecture diagram

Deploy the Application

The below steps walk you through deploying the application to AWS using the AWS Serverless Application Model (SAM). The deployment process packages your Lambda function code, uploads artifacts to Amazon S3, and provisions all required AWS resources including Lambda functions, IAM roles, and any configured VPC networking via AWS CloudFormation.

Prerequisites

Make sure you have the following tools installed locally:

  • AWS CLI configured with credentials
  • SAM CLI installed
  • Python 3.13+ installed locally
  • Docker or Finch (required for container builds)
  • AWS account with appropriate permissions
  • A VPC with at least 2 subnets (across different Availability Zones) and a security group — required for the Lambda Managed Instances capacity provider
  • Supported regions: Check AWS Capabilities by Region for supported regions

Getting Started

The complete source code for this application is available in our GitHub repository. To deploy it yourself follow the below steps and refer to the full deployment instructions hosted on GitHub.

1. Clone the repository

git clone https://github.com/aws-samples/sample-lambda-managed-instances-analytics.git

2. Navigate to the project folder

cd sample-lambda-managed-instances-analytics

chmod +x setup-data.sh deploy-lambda.sh

3. Generate sample data and upload to S3

./setup-data.sh

This script will create an S3 bucket (if needed), generate 1M rows of sample data, and upload the data to S3.

4. Build and deploy the Lambda function

./deploy-lambda.sh

This script will build the container image with FastEmbed, push it to ECR, and deploy the Lambda function along with Capacity Provider, API Gateway, and Cognito User Pool. After deployment, it automatically generates the UI authentication configuration and prompts you to create a test user.

SAM template

Capacity provider configuration

Run the Application

1. Start the UI

The application includes a simple HTML-based UI through which you can test the AWS Lambda function using Amazon API Gateway:

cd ui && python3 -m http.server 8000

2. Open your browser at http://localhost:8000 and click ‘Sign In’ to authenticate via Cognito using the username/password that you created during deployment

Starting the UI

3. Enter your API endpoint URL. Test connection and click system Info.

Testing the connection

Test the Application

a. Customer Analysis — Enter one or more User IDs to get more information on the customer behavior: engagement scores, conversion rates, purchase patterns, and AI-generated customer segments

Running customer analysis

b. Semantic Search – Enter natural language queries like “list high value customers from USA” in the Semantic Search and verify the results. Note that the response is very fast as the analytics data and FastEmbed models are loaded into memory during init stage

Running semantic search

c. Cohort Analysis — Enter the query data to get Real-time segmentation by device, country, age group with aggregated metrics

Running cohort analysis

Observability

AWS Lambda Managed Instances automatically publishes metrics to Amazon CloudWatch, giving you visibility into function performance and capacity utilization. Monitor InitDuration to track dataset and model load time at startup, MaxMemoryUsed to confirm your data fits within configured memory, and ProvisionedConcurrencySpilloverInvocations to detect when AWS Lambda Managed Instances capacity is exhausted.

Enable AWS Lambda Insights for enhanced per-invocation metrics including CPU time and memory utilization over time. Use Amazon CloudWatch Log Insights to query INIT_START, INIT_END, and REPORT log entries for initialization and memory details per invocation.

AWS Lambda Insights

What Makes This Better with AWS Lambda Managed Instances

Without AWS Lambda Managed Instances, building this same application would require one of these alternatives:

  • Option A: EC2 with auto-scaling — Full control, full responsibility: patching, scaling policies, load balancing, and deployment pipelines — all on you.
  • Option B: Redesign for standard Lambda — Swap in-memory data for an external database and replace the ML model with Amazon SageMaker endpoint. More latency, more cost, more complexity.

With AWS Lambda Managed Instances, you write a single AWS Lambda function, define a Capacity Provider, and deploy with SAM. AWS Lambda handles the Amazon EC2 instances, scaling, and lifecycle, giving you the memory you need with the operational simplicity you want. The in-memory approach eliminates network latency and disk I/O, delivering consistent sub-200ms response times for complex analytics.

Cost Considerations

AWS Lambda Managed Instances uses Amazon EC2-based pricing with a management fee. For predictable workloads, you can leverage Amazon EC2 Savings Plans or Reserved Instances to reduce costs significantly.

Example cost comparison (us-east-1, 32 GB memory, 1M invocations/month):

  • AWS Lambda (standard): ~$267/month (on-demand pricing)
  • AWS Lambda Managed Instances: ~$180/month (with 1-year Compute Savings Plan)
  • Savings: 33% reduction

The cost benefits increase with higher memory configurations and sustained workloads that can take advantage of Amazon EC2 pricing discounts.

Best Practices

Based on experience building this solution, here are key recommendations:

  • Memory sizing: Start with your dataset size plus 50% overhead for processing. Monitor Amazon CloudWatch metrics to optimize.
  • Initialization strategy: Load large datasets during the init phase to amortize the cost across multiple invocations.
  • Concurrency configuration: Set PerExecutionEnvironmentMaxConcurrency based on your workload’s I/O characteristics. Higher values work well for I/O-bound analytics.
  • Data format: Use columnar formats like Parquet for efficient memory usage and fast loading.
  • Monitoring: Track initialization duration, memory utilization, and invocation latency in Amazon CloudWatch to identify optimization opportunities.

Cleanup

When you’re done exploring the solution, it’s good practice to remove all provisioned resources to avoid ongoing charges. For the full cleanup commands and exact steps, refer to the project’s README.md in GitHub repository.

Conclusion

AWS Lambda Managed Instances opens up a new class of serverless applications that support larger AWS Lambda layer packages and more memory. Memory-intensive workloads — in-memory analytics, ML inference, graph processing, scientific computing — can now run with the simplicity of AWS Lambda and the resources of Amazon EC2. The customer analytics example demonstrates how in-memory processing with AWS Lambda Managed Instances delivers performance improvements over traditional database queries while maintaining serverless benefits like automatic scaling and pay-per-use pricing.

Ready to get started? Explore the AWS Lambda Managed Instances documentation and try building your own memory-intensive serverless application. You can find the complete code for this example on GitHub.

Optimizing storage performance for Amazon EKS on AWS Outposts

Post Syndicated from Arun Kumar original https://aws.amazon.com/blogs/compute/optimizing-storage-performance-for-amazon-eks-on-aws-outposts/

Amazon Elastic Kubernetes Service (Amazon EKS) on AWS Outposts brings the power of managed Kubernetes to your on-premises infrastructure. Use Amazon EKS on Outposts rack to create hybrid cloud deployments that maintain consistent AWS experiences across environments. As organizations increasingly adopt edge computing and hybrid architectures, storage optimization and performance tuning become critical for successful workload deployment.

Outposts extend AWS infrastructure, services, APIs, and tools to virtually any datacenter, co-location space, or on-premises facility. In this blog post you will learn about your storage options and their performance characteristics which is essential for building resilient, high-performing applications using Amazon EKS on Outposts.

Amazon EKS on Outposts deployment options

The following two sections outline the differences between Amazon EKS extended and local cluster deployment options available on Outposts.

Amazon EKS extended cluster architecture

Amazon EKS extended clusters on Outposts provide a powerful solution for organizations seeking to use the benefits of Kubernetes while maintaining certain workloads on-premises, as shown in the following figure. This hybrid architecture allows businesses to extend their EKS clusters from the AWS Cloud to their own data centers or edge locations using Outposts. The Kubernetes control plane remains in the AWS Region, providing centralized management and benefiting from the AWS infrastructure in the cloud and on the Outpost.

Outposts is designed to be a connected service, and needs reliable network connectivity to the AWS Region using the Outposts service link.

Figure 1 : Extended cluster

Amazon EKS local cluster architecture

Amazon EKS local clusters deploy the Kubernetes control plane on your Outpost, as shown in the following figure. This provides greater network resilience against outages as cluster operations run entirely on the Outposts and reduces the dependency on network connectivity to the AWS Region. Having the Kubernetes control plane hosted on your Outpost also reduces latency for cluster operations.

  Figure 2: Local cluster

Storage options for Amazon EKS extended clusters on Outposts

Persistent Volumes (PV) and Persistent Volume Claims (PVC) serve as a critical abstraction layer in Kubernetes, separating the storage consumption details from storage provisioning, and allowing administrators to manage storage resources independently from how applications consume them. PVs and PVCs make sure of data persistence across pod restarts and rescheduling events, making them essential for applications that need to maintain state, such as databases, file storage systems, and other data-intensive workloads. The abstraction provided by PV and PVC enables platform-agnostic storage management, where applications can request storage through PVCs without needing to know the underlying storage implementation details. PVs and PVCs support dynamic provisioning through Storage Classes, allowing for automated storage allocation based on application demands, while also providing features such as access modes, capacity management, and reclaim policies to effectively manage the storage lifecycle in a Kubernetes cluster.

Integrating Amazon EBS with Amazon EKS

Amazon Elastic Block Store (Amazon EBS) provides high-performance block storage that’s ideal for low-latency applications providing consistent performance. When deployed on Outposts racks, EBS volumes are stored on the Outposts hardware, providing significant performance advantages over network-attached storage solutions, as shown in the following figure.

Figure 3 : Integrating Amazon EBS with Amazon EKS on Outposts

Benefits and use cases

  • Storage: EBS volumes on Outposts racks provide data access without dependency on external connectivity.
  • Performance: Local storage delivers consistent latency and high IOPS/throughput.
  • Cost: On-premises storage eliminates data transfer costs and reduces bandwidth needs, lowering the total cost of ownership.

Implementation considerations

Consider the following when using EBS on Outposts rack:

  • EBS volumes on Outposts are tied to a single rack and the availability zone the Outpost is homed to, needing applications to address single-point-of-failure risks.
  • Protect data using EBS snapshots in the parent Region and schedule regular backups.
  • Capacity on Outposts is finite, monitor Outposts storage usage and plan expansions proactively to avoid insufficient capacity errors.

Refer to Dynamic Volume Provisioning to learn more about deploying pod with the EBS volume attached.

Amazon EFS with Amazon EKS

Amazon Elastic File System (Amazon EFS) provides scalable, shared file storage that can be accessed across multiple AWS Availability Zones (AZs) and on-premises environments. Although Amazon EFS with Amazon EKS on Outposts maintains the same setup procedures as standard cloud deployments, there is a critical dependency on the service link connection between your Outposts and the AWS Region. Amazon EFS is not a locally supported service on Outposts, so connectivity to the AWS Region is required to use this service with your Outpost.

Amazon EFS allows multiple pods to concurrently access shared file systems. It is well-suited for applications that need collaborative data access, content management, and distributed processing workloads.

Amazon EFS as a persistent storage solution for Amazon EKS extended cluster instances

Amazon EFS as a PV for your Amazon EKS extended cluster operates through a hybrid architecture where the Amazon EFS file system resides in the Region, but mount points can be created on the worker nodes running on Outposts subnets through the service link as shown in the following figure.

Figure 4 : Amazon EFS as a persistent storage solution for extended clusters

Benefits and use cases

  • Shared storage capabilities: multiple pods can access a centralized file system, enabling shared data, code, and assets across instances.
  • Scalability: storage capacity and performance automatically scale with usage, eliminating manual provisioning and upfront planning.
  • Compliance: Amazon EFS provides full file system features and compatibility for traditional applications, such as locking, permissions, and directory structure.

Challenges and limitations

Consider the following when using Amazon EFS with Outposts:

  • Network latency: file access involves network traversal to Amazon EFS in the Region, adding more latency and making small or metadata operations potentially slow for latency-sensitive applications.
  • Throughput: aggregate throughput is restricted by the available bandwidth on the service link between the Outposts and AWS Region. This impacts concurrent access and large file transfers during peak usage.
  • Dependency on AWS Region connectivity: Amazon EFS needs continuous connectivity to the parent Region. Disruptions may affect file system availability, operations, and disaster recovery processes.
  • Data Transfer charges: Since EFS is in AWS Parent region and EKS worker nodes and pods are in Outpost additional charges are applicable.

You can refer to Amazon EFS Features and When to Choose Amazon EFS for more detailed insights into its capabilities and use cases.

Deploying pods on extended clusters using Amazon EFS as PV

Refer to Use Elastic File System Storage with Amazon EFS for deployment guidance. Note, Create Amazon EFS mount targets in subnets that are in the same Availability Zone (AZ) as the Outposts subnets.

Amazon S3 with Amazon EKS extended cluster

Amazon Simple Storage Service (Amazon S3) on Outposts delivers local object storage on your Outposts, allowing applications to use Amazon S3 APIs for storing and retrieving data while keeping it onsite. It is ideal for workloads that need Amazon S3 compatibility, low latency access to object data, and local data residency.

You should use Amazon S3 access point Amazon Resource Names (ARNs) and not bucket ARNs for proper integration with Amazon EKS workloads.

Learn more about Amazon S3 on Outposts.

Figure 5 : Amazon S3 with Amazon EKS extended cluster on Outposts

Benefits and use cases

  • Data archiving and compliance: Enables cost-effective, locally retained storage for logs, audit trails, regulatory compliance, backups, and sensitive healthcare data with strict residency requirements.
  • Content distribution and media: Provides ultra-low latency local storage for serving static content, media streaming, digital asset management, and gaming asset delivery.
  • Data lake and analytics: Supports local data processing for analytics, ETL, machine learning (ML), real-time Internet of Things (IoT) data handling, and business intelligence with reduced latency and transfer costs.
  • Application integration: Seamlessly integrates with Amazon S3 compatible apps for backup, synchronization, microservices storage, API-driven workflows, and container image management on-premises.

Refer to How is Amazon S3 on Outposts different from Amazon S3 and the Amazon S3 on Outposts documentation to learn more.

Deploying pods on extended clusters using Amazon S3 as PV

Step 1: Create Amazon S3 on Outposts bucket
Step 2: Create Amazon S3 Access Point (necessary for Amazon EKS integration)
Step 3: Configure IAM roles and policies
Step 4: Install Amazon S3 CSI driver
Step 5: Deploying your pod with Amazon S3 volume attached
Step 6: Complete Amazon S3 configuration with Kubernetes

Refer to the documentation Static Provisioning on Outposts bucket for more details on Step 5.

Best practices for optimizing performance

Optimizing performance starts with selecting the right storage type for your workload: Amazon EBS for low-latency, high-throughput block storage; Amazon EFS for shared POSIX-compliant file systems; and Amazon S3 for scalable object storage with API compatibility. Ensure proper volume sizing, monitor usage proactively, and configure CPU and memory requests accurately to balance performance and efficiency—auto scaling and QoS classes can further optimize resource management. Improve data locality by using local storage, apply caching with intelligent eviction, and design for efficient, asynchronous, and compressed data access patterns.

Monitoring and observability

Monitoring key performance metrics is essential to maintain storage efficiency and application reliability. For Amazon EBS, track IOPS, throughput, latency, burst balance, queue depth, and snapshot performance to avoid degradation—see the Amazon CloudWatch metrics for Amazon EBS for the full list. For Amazon EFS, monitor total I/O, throughput, client connections, metadata operations, burst credits, and Regional data transfers to support effective capacity planning—refer to CloudWatch metrics for Amazon EFS. For Amazon S3, observe request and error rates, data transfer, storage usage, latency, multipart upload efficiency, and access patterns to optimize performance and cost—see Metrics and dimensions.

Security considerations

Strong security practices are critical for Amazon EKS on Outposts. Use AWS Key Management Service (AWS KMS) for Amazon EBS encryption, encrypt Amazon EFS data at rest and in transit, and enable server- or client-side encryption for Amazon S3. Enforce TLS for all data transfers and apply key rotation with compliance controls. Implement least privilege IAM policies, scoped roles, and Kubernetes Role-Based Access Control (RBAC) for granular pod access. Secure traffic with security groups and NACLs, and maintain audit logs for all storage operations.

Cost optimization strategies

Manage storage costs by right-sizing volumes, automating lifecycle policies, selecting appropriate storage classes, monitoring data transfer, and using de-duplication and compression where applicable. Lower operational expenses through automated backups, infrastructure as code (IaC), monitoring automation, leveraging managed services, applying cost allocation tags, and conducting regular usage reviews.

Conclusion

Amazon EKS on Outposts empowers organizations to build hybrid applications with storage options that align to performance, compliance, and data residency needs. By selecting the right storage solution for each workload and leveraging Outposts’ local infrastructure, you can reduce latency, minimize network dependencies, and maintain consistency across environments. As Outposts capabilities continue to evolve, they offer a strong foundation for modern, resilient, and cost-efficient hybrid cloud architectures.

Reach out to your AWS account team, or fill out this form to learn more about running containarized applications on Outposts.

Authorizing access to data with RAG implementations

Post Syndicated from Riggs Goodman III original https://aws.amazon.com/blogs/security/authorizing-access-to-data-with-rag-implementations/

Organizations are increasingly using large language models (LLMs) to provide new types of customer interactions through generative AI-powered chatbots, virtual assistants, and intelligent search capabilities. To enhance these interactions, organizations are using Retrieval-Augmented Generation (RAG) to incorporate proprietary data, industry-specific knowledge, and internal documentation to provide more accurate, contextual responses. With RAG, LLMs use an external knowledge base that uses a vector store to incorporate specific knowledge data before generating responses.

Our customers have told us that they’re concerned adding additional context to prompts will lead to leakage of sensitive information to principals (persons or applications) that might exist in some of these tools or to unstructured data within the knowledge base. As mentioned in previous posts (Part 1, Part 2), LLMs should be considered untrusted entities because they do not implement authorization as part of a response. A good mental model for organizations is to assume that any data passed to an LLM as part of a prompt could be returned to the principal. With tools (APIs that an LLM can invoke to interact with external resources), you can pass the identity tokens of the principal to the tool to determine what the principal is permitted to access and actions that are allowed. Capabilities across different vector databases—including metadata filters and syncing identity information between the data source and the knowledge base—support providing better results from the knowledge base and provide a baseline filtering capability. This does not provide for strong authorization capabilities using the data source as the source of truth, which some customers are looking for.

In this blog post, I show you an architecture pattern for providing strong authorization for results returned from knowledge bases with a walkthrough example of this using Amazon S3 Access Grants with Amazon Bedrock Knowledge Bases. I also provide an outline of considerations when implementing similar architecture patterns with other data sources.

RAG usage overview

RAG architectures share similarities with search engines but have key differences. While both use indexed data sources to find relevant information, their approaches to data access differ. Search engines provide links to information sources, requiring users to access the original data source directly based on their permissions. This flow is shown in Figure 1.

Figure 1 – A principal, User in this example, accessing a data source after the search engine returns results

Figure 1: A principal, User in this example, accessing a data source after the search engine returns results

Unlike search engines, RAG implementations return vector database results directly from the LLM, bypassing permission checks at the original data source. While metadata filtering can help control access, it presents two key challenges. First, vector databases only sync periodically, meaning permission changes in the source data aren’t immediately reflected. Second, complex identity permissions—where principals might belong to hundreds of groups—make it difficult to accurately filter results. This makes metadata filtering insufficient for organizations that require stronger authorization controls. This flow is shown in Figure 2.

Figure 2 – An application accessing data in a vector database

Figure 2: An application accessing data in a vector database

To implement robust authorization for knowledge base data access, verify permissions directly at the data source rather than relying on intermediate systems. When using the search engine example, access verification occurs when retrieving the actual result from the data source, not during the initial search. For vector databases, the generative AI application validates access rights by sending an authorization request to the data source before retrieving the data. This helps make sure that the data source that maintains the authoritative access control rules determines whether the principal has permission to access specific objects. This real-time authorization check means permission changes are immediately reflected when accessing the data source. This authorization pattern is similar to how AWS Lake Formation manages access to structured data. Lake Formation evaluates permissions when a principal requests access to databases or tables, granting or denying access based on the principal’s defined permissions. You can implement comparable authorization controls for vector database results before providing that context to large language models.

Let’s look at a solution using S3 Access Grants with Amazon Bedrock Knowledge Bases as an example use case.

Solution overview: S3 Access Grants with Bedrock Knowledge Bases

In the following example, you have an ACME organization that wants to create a generative AI chatbot for their employees. There are multiple teams within the organization (Marketing, Sales, HR, and IT) that work on projects throughout the organization. You have five users (the principals accessing the application) with the following group permissions:

  • Alice: Marketing Team
  • Bob: Sales Team, Project A Team
  • Carol: HR Team, Project B Team
  • Dave: IT Support, Project C Team
  • Eve: Marketing Team

Each principal will have access to their respective project (for example /projects/projectA) or department folders (for example departments/marketing/). Marketing also will have access to everything in the projects folder (/projects/*) unless they are considered highly confidential files. To mark Project B files as highly confidential, you will include a metadata tag for objects within the Project C prefix with classification = ‘highly confidential’. Figure 3 shows the relationship between the principals and access to the different folders within the data source. As an example, only Carol has access to highly confidential data in the Project B folder.

Figure 3 – Group permissions for the organization

Figure 3: Group permissions for the organization

To authorize access for each principal to the objects within the knowledge base, you will use Amazon S3 Access Grants. You can learn how to set up S3 Access Grants in Part 1 or Part 2 of the blog series.

Within AWS IAM Identity Center, you will add each user to their respective groups. Bob will be added to both the Sales Team group and Project A Team group, similar to what is shown in Figure 3.

Each prefix (projectA/, marketing/) will have a single file that provides a status for the team. In addition, for Project B, you will also add a status.txt.metadata.json file to tag the object as highly confidential, because it’s a HR project. For example, for Project B, the status.txt file looks like the following:

Project B status is as follows:
Project B = Compensation Update
STATUS = YELLOW
Project completion = 50%
Notes: we are tracking behind schedule. Need to pull more resources to get it completed by next month.

And the metadata.json file is as follows:

{
    "metadataAttributes" : { 
        "classification" : "highly confidential"
    }
}

After the knowledge base and S3 access grants are configured, you can now test the authorization of knowledge base chunks. The application flow is the following, as shown in Figure 4:

  1. The user uses their identity provider (IdP) to sign in to the generative AI application (steps 1a, 1b, and 1c).
  2. The generative AI application exchanges a token with IAM Identity Center and assumes the role on behalf of the user (step 2).
  3. The generative AI application calls S3 Access Grants to get a list of the grants the user is authorized to access (step 3).
  4. The user sends a query to the generative AI application (step 4).
  5. The generative AI application sends a query to knowledge base (step 5).
  6. The generative AI application reviews chunks from the knowledge base against the scopes the user is authorized to access (step 6).
  7. Only scopes the user is authorized to will be passed to the LLM for a response (step 7).
  8. The generative AI application will continue steps 5–7 until you want to get a new list of authorized scopes (repeat step 4) or the token expires (repeat steps 3 and 4).
Figure 4 – Application flow to authorize data from knowledge bases

Figure 4: Application flow to authorize data from knowledge bases

The grant scopes are shown in the following table:

Grant scope Grant ID
s3:// amzn-s3-demo-bucket/departments/sales/* edbd7575-0ba8-4837-8df1-07fe5d89f973 (sales group)
s3:// amzn-s3-demo-bucket/departments/it/* a8f1d390-10d1-7037-7b27-c9fcf0b04441 (it group)
s3:// amzn-s3-demo-bucket/departments/marketing/* 28f1e3c0-8081-70fe-6b4f-531ae370e7fd (marketing group
s3:// amzn-s3-demo-bucket/departments/hr/* 38f11380-d011-70fb-261b-aa50d7edc1d5 (hr group)
s3:// amzn-s3-demo-bucket/projects/projectA/* c84173b0-b071-70c5-3207-dadc1e6f76a9 (project A group)
s3:// amzn-s3-demo-bucket/projects/projectB/* 2871d3c0-6001-7073-baaf-62717f56b8d0 (project B group)
s3:// amzn-s3-demo-bucket/projects/projectC/* f8a183b0-f001-707b-aa8e-1826ca04595e (project C group)
s3:// amzn-s3-demo-bucket/projects/* 28f1e3c0-8081-70fe-6b4f-531ae370e7fd (marketing group)

For this example, you can use Bob’s role to demonstrate how chunk authorization works. When you call the knowledge base without performing any data authorization, you receive the following back when asking “What is the status of my project.” With each object within the data source, you also include meta data, in the form of *.metadata.json, which is used by the knowledge base to assign specific key/value pairs to each object. This is where you add the classification for Projects A and C as confidential and Project B as highly confidential, as mentioned previously. You pass this filter as part of the Bedrock knowledge base request, using a RetrievalFilter within the retrievalConfiguration. The following code shows the response from the Bedrock knowledge base:

{
    "ResponseMetadata": {
        ...
    },
    "retrievalResults": [
        {
            "content": {
                "text": "Project A status is as follows:  Project A = Sales Strategy STATUS = GREEN Project completion = 80% Notes:  we are on track to complete the project by end of month",
                "type": "TEXT"
            },
            "location": {
                "s3Location": {
                    "uri": "s3://amzn-s3-demo-bucket/projects/projectA/status.txt"
                },
                "type": "S3"
            },
            "metadata": {
                "x-amz-bedrock-kb-source-uri": "s3://amzn-s3-demo-bucket/projects/projectA/status.txt",
                "classification": "confidential",
                "x-amz-bedrock-kb-chunk-id": "1%3A0%3AnTT-15UBTG7d8qG4nL6p",
                "x-amz-bedrock-kb-data-source-id": "CIUUDCONV2"
            },
            "score": 0.558023
        },
        {
            "content": {
                "text": "Project C status is as follows:  Project C = Infrastucture Update STATUS = RED Project completion = 30% Notes:  ROI is not meeting expectations, rethinking strategy with project",
                "type": "TEXT"
            },
            "location": {
                "s3Location": {
                    "uri": "s3://amzn-s3-demo-bucket/projects/projectC/status.txt"
                },
                "type": "S3"
            },
            "metadata": {
                "x-amz-bedrock-kb-source-uri": "s3://amzn-s3-demo-bucket/projects/projectC/status.txt",
                "classification": "confidential",
                "x-amz-bedrock-kb-chunk-id": "1%3A0%3AnDT-15UBTG7d8qG4mb78",
                "x-amz-bedrock-kb-data-source-id": "CIUUDCONV2"
            },
            "score": 0.52052265
        }
    ]
} 

The data from Project B isn’t included in the output because it’s tagged as highly confidential. Data from Project C is included, which Bob shouldn’t have access to, so let’s step through how to authorize Bob to the correct data.In the following steps and using the provided sample Python code, I will walk through calling each one of the functions shown in the following code block. You can use this code as part of your application to validate permissions for data returned from the Bedrock knowledge base.

# Execute the workflow
# 1. Assume role for S3 access
client_s3_oidc = assume_role(
   args.client_id, args.grant_type, args.assertion,
   args.role_arn, args.role_session_name, args.provider_arn
)
    
# 2. Get caller's authorized S3 scopes
scopes = get_caller_grant_scopes(client_s3_oidc, args.account)
        
# 3. Filter chunks based on caller's authorization
authorized, not_authorized = check_grant_scopes(chunks, scopes)

Step 1: User uses the IdP to sign in to the generative AI application

When Bob first accesses the generative AI application, the application will redirect him using a single sign-on flow for him to authenticate with their IdP. Bob will receive a signed identity token from the IdP that will validate who Bob is from an identity perspective. An example identity token for Bob is shown in the following example:

{
    "sub": "sub",
    "email": "[email protected]",
    "aud": "bob",
    "iss": "https://tokens.identity-solutions.example.com",
    "exp": 1744219319,
    "iat": 1744218719,
    "name": "bob"
}

Step 2: Token exchange with IAM Identity Center

After Bob is authenticated and passes his token to the generative AI application, the application will exchange the identity token from the IdP with the IAM Identity Center identity token and retrieve temporary credentials on behalf of Bob. You will create a function called assume_role in Python that passes multiple different variables used to allow Bob to assume a role inside AWS:

  • client_id: The unique identifier string for the client or application. This value is an application Amazon Resource Name (ARN) that has OAuth grants configured.
  • grant_type: OAuth grant type, which for our example will be JWT Bearer.
  • role_arn: The ARN of the role to assume.
  • role_session_name: An identifier for the assumed role session.
  • provider_arn: The context provider ARN from which the trusted context assertion was generated.
  • client_assertion: This value specifies the JSON Web Token (JWT) issued by a trusted token issuer.

In the sample Python function, shown in the following example code, you will perform the following steps:

  1. You open both a boto3 client for sso-oidc (to create a token with IAM) and sts (to assume the temporary role for Bob).
  2. Next, you will use the client_id, grant_type, and client_assertion to call create_token_with_iam to create an IAM Identity Center token that is passed back to the token_response variable.
  3. Within the token_response, there is an sts:identity_context that is needed to assume the role for Bob.
  4. With the identity_context, you pass the identity context to assume_role with the role_arn, role_session_name, and provider_arn to retrieve temporary credentials for Bob.
  5. Lastly, you return to the application a boto3 client for s3-control that uses Bob’s temporary credentials to validate his authorization with S3 access grants.
def assume_role(client_id, grant_type, client_assertion, role_arn, role_session_name, provider_arn):
    """
    Assume an IAM role using SSO/OIDC authentication and return an S3 control client.
    
    Args:
        client_id: The ID of the OIDC client
        grant_type: The type of grant being requested
        client_assertion: The client assertion token
        role_arn: ARN of the role to assume
        role_session_name: Name for the temporary session
        provider_arn: ARN of the identity provider
        
    Returns:
        boto3.client: An S3 control client with temporary credentials
    """
    client_oidc = boto3.client('sso-oidc')
    client_sts = boto3.client('sts')
    try:
        # Get ID token from IAM using SSO OIDC
        token_response = client_oidc.create_token_with_iam(
            clientId=client_id,
            grantType=grant_type,
            assertion=client_assertion
        )
        
        # Extract identity context from token
        id_token = jwt.decode(token_response['idToken'], options={'verify_signature': False})
        identity_context = id_token['sts:identity_context']
        
        # Assume role using identity context
        temp_credentials = client_sts.assume_role(
            RoleArn=role_arn,
            RoleSessionName=role_session_name,
            ProvidedContexts=[{
                'ProviderArn': provider_arn,
                'ContextAssertion': identity_context
            }]
        )
        
        # Create and return S3 control client with temporary credentials
        creds = temp_credentials['Credentials']
        return boto3.client(
            's3control',
            region_name='us-west-2',
            aws_access_key_id=creds['AccessKeyId'],
            aws_secret_access_key=creds['SecretAccessKey'],
            aws_session_token=creds['SessionToken']
        )
    except ClientError as e:
        print(f'Error: {e}')
        sys.exit(1)

Step 3: Retrieve the caller grant scopes

Next, you need to retrieve what Bob is allowed to access in the data source by using S3 Access Grants. In our example, you need to validate the data Bob is authorized to access with the data source, not the S3 object itself. To obtain the prefixes Bob is authorized to access, you will need to do the following in the get_caller_grant_scopes function.

  1. First, you will pass the s3control client that was returned from assume_role. in addition to the account for the S3 access grants.
  2. With the temporary role for Bob, you will call list_caller_access_grants. This will return a list of caller access grants available to Bob. So, for example, when you call this for Bob, you would receive the following response from list_caller_access_grants, where you can see he has access to the sales prefix and projectA prefix. This is shown in the following example code.
{
    "ResponseMetadata": {
        ...
    },
    "CallerAccessGrantsList": [
        {
            "Permission": "READ",
            "GrantScope": "s3:// amzn-s3-demo-bucket/departments/sales/*",
            "ApplicationArn": "ALL"
        },
        {
            "Permission": "READ",
            "GrantScope": "s3:// amzn-s3-demo-bucket/projects/projectA/*",
            "ApplicationArn": "ALL"
        }
    ]
}
  1. You add the scopes to an array and return the array back to the application. The code example for this follows. Note: you remove the * from the access grant, because the chunk URI is the full path, not just the prefix.
def get_caller_grant_scopes(client, account):
    """
    Retrieve the S3 access scopes granted to a caller.
    
    Args:
        client: S3 control client with assumed role credentials
        account: AWS account ID
        
    Returns:
        List of S3 path prefixes the caller is authorized to access
    """
    try:
        # Get list of access grants for the caller
        response = client.list_caller_access_grants(AccountId=account)
        
        # Extract S3 path prefixes and remove trailing wildcards
        scopes = [grant['GrantScope'].replace('*','') for grant in response['CallerAccessGrantsList']]
        return scopes
    except ClientError as e:
        print(f'Error: {e}')
        sys.exit(1)

At this point, you have a list of the grant scopes that Bob is authorized to access in the data source. This information can now be used to check against chunks that are returned from the knowledge base to authorize access to the data before passing the final prompt with additional context to the LLM.

Step 4: Check caller grant scopes

The last step is to check chunks returned by the knowledge base against the list of the grants Bob has access to. For this, you define check_grant_scopes and pass both the chunks and the scopes Bob is authorized to access. The variable chunks is an array of dictionaries that you will parse, validating it against the list of scopes, shown in the following code example.

  1. You first loop through each chunk that was passed to the function.
  2. For each chunk, you will check to see if the chunk location starts with a given prefix that is in the S3 access grant.
  3. If a match is found, you add it to the chunk, along with the scope found in the S3 access grant, to the list of e chunks. If a match is not found in the scopes, then you add it to the not_authorized chunks.

The function will return both the list of authorized chunks and not_authorized chunks to provide visibility into the different chunks Bob was denied access to.

def check_grant_scopes(chunks, scopes):
    """
    Check which chunks a user is authorized to access based on their granted scopes.
    
    Args:
        chunks: List of dictionaries containing content chunks with 'location' keys
        scopes: List of authorized S3 path prefixes the user has access to
        
    Returns:
        tuple: (authorized_chunks, unauthorized_chunks)
    """
    authorized = []
    not_authorized = []
    # If user has no scopes, they are not authorized for any chunks
    if not scopes:
        return [], chunks
    
    # Check each chunk against available scopes
    for chunk in chunks:
        location = chunk['location']
        authorized_scope = next((scope for scope in scopes if location.startswith(scope)), None)
        
        if authorized_scope:
            chunk['scope'] = authorized_scope
            authorized.append(chunk)
        else:
            not_authorized.append(chunk)
    
    return authorized, not_authorized

When running the preceding function for Bob and the chunks returned from the knowledge base, you get the following authorized chunks and not authorized chunks as shown in the following example. The authorized chunks are added to the query, which is then passed to the LLM, returning a response.

# Authorized:
[
    {
        "content": "Project A status is as follows:  Project A = Sales Strategy STATUS = GREEN Project completion = 80% Notes:  we are on track to complete the project by end of month",
        "location": "s3://amzn-s3-demo-bucket/projects/projectA/status.txt",
        "scope": "s3://amzn-s3-demo-bucket/projects/projectA/"
    }
]
# Not Authorized:
[
    {
        "content": "Project C status is as follows:  Project C = Infrastucture Update STATUS = RED Project completion = 30% Notes:  ROI is not meeting expectations, rethinking strategy with project",
        "location": "s3://amzn-s3-demo-bucket/projects/projectC/status.txt"
    }
]

Solution considerations

When implementing this authorization architecture for RAG implementations, it’s important to understand several key considerations that impact security, performance, and scalability. These considerations help make sure your implementation maintains strong security controls, while optimizing system performance and providing flexibility for different data sources. The following points outline important aspects to evaluate when designing and implementing this authorization pattern:

  • For this example, you used S3 Access Grants as the example of how to check for authorization. However, this architecture can be used with your choice of data source, if the URI for the data source is returned from the knowledge base and there is an API that can be called to validate what a principal is authorized to access, like the get_caller_grant_scopes function described previously.
  • The use of S3 Access Grants provides authorization for a principal to access the data source. Additional access control policies could be applied to each bucket by adding a key/value tag or data source if desired. By doing this, the principal would be denied access to the bucket even though S3 Access Grants provides authorization. To support this functionality, you can add metadata for the vector database to ingest and filter on the query to the knowledge base, as shown in the preceding example.
  • Similar to stale data until resync of the knowledge base, the list of authorized scopes can also become stale. It’s up to you to decide how often you refresh the list of authorized scopes (step 3 in Figure 4) and the duration of the assume role of the principal (step 2 in Figure 4).
  • Depending on the chunks the principal is authorized to access and what the knowledge base returns, chunks could be dropped before sending to the LLM. From a security point of view, this is preferred so principals will not get access to chunks they aren’t authorized to. From an architecture point of view, you should optimize the knowledge base query and add additional metadata tags to limit the number of non-authorized chunks returned from the knowledge base. This is one reason to include a not_authorized list as part of the check_grant_scopes function.

Conclusion

In this post, I showed you an architecture pattern to provide strong authorization for results returned from knowledge bases. You walked through the importance of strong authorization with knowledge bases and how to implement authorization with Amazon S3 Access Grants. Lastly, you walked through code examples of how this would work in practice using Amazon Bedrock Knowledge Bases with S3 Access Grants.


For additional information on generative AI security, take a look at other posts in the AWS Security Blog and AWS blog posts covering generative AI.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
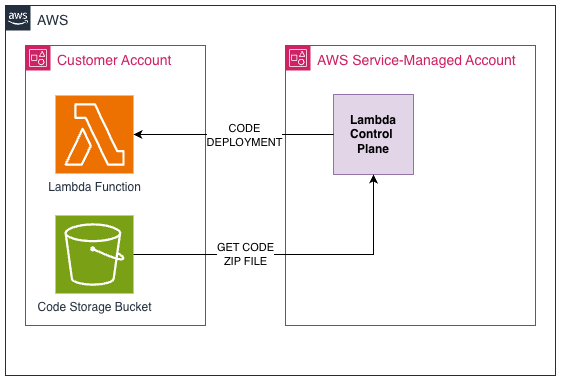
Riggs Goodman III

Riggs Goodman III

Riggs is a Principal Partner Solution Architect at AWS. His current focus is on AI security and networking, providing technical guidance, architecture patterns, and leadership for customers and partners to build AI workloads on AWS. Internally, Riggs focuses on driving overall technical strategy and innovation across AWS service teams to address customer and partner challenges.

Secure file sharing solutions in AWS: A security and cost analysis guide: Part 2

Post Syndicated from Swapnil Singh original https://aws.amazon.com/blogs/security/secure-file-sharing-solutions-in-aws-a-security-and-cost-analysis-guide-part-2/

As introduced in Part 1 of this series, implementing secure file sharing solutions in AWS requires a comprehensive understanding of your organization’s needs and constraints. Before selecting a specific solution, organizations must evaluate five fundamental areas: access patterns and scale, technical requirements, security and compliance, operational requirements, and business constraints. These areas cover everything from how files will be shared and what protocols are needed, to security measures, day-to-day operations, and business limitations.

See Part 1 of this series for detailed information about each of these fundamental areas and their specific considerations. Part 1 also covers solutions including AWS Transfer Family, Transfer Family web apps, and Amazon Simple Storage Service (Amazon S3) pre-signed URLs. This part continues our analysis with additional AWS file sharing solutions to help you make an informed decision based on your specific requirements.

Solutions

Let’s start by looking at the various file sharing mechanisms that AWS supports. The following table identifies the key AWS services needed for each solution, describes the security and cost implications of the solutions, and describes their complexity and protocol support capabilities.

Solution AWS services Security features Cost* Region control
CloudFront signed URLs CloudFront, Amazon S3, and Lambda Optional edge security using AWS Lambda@Edge, WAF integration, SSL/TLS, geo restrictions, and AWS Shield Standard (included automatically) Content delivery network (CDN) costs, request pricing, and data transfer fees Global service by design; origin can be AWS Region-specific
Amazon VPC endpoint service AWS PrivateLink, Amazon VPC, and Network Load Balancer (NLB) Complete network isolation, private connectivity, and multi-layer security Endpoint hourly charges, NLB costs, and data processing fees Service endpoints are strictly Region-specific; must create endpoints in each Region where access is needed
S3 Access Points Amazon S3, IAM, Amazon VPC (for VPC-specific access points)
  • Dedicated IAM policies per access point
  • VPC-only access restrictions available
  • Works with bucket policies for layered security
  • Supports PrivateLink for private network access
  • Compatible with S3 Block Public Access settings
  • No additional charge for S3 Access Points
  • Standard S3 request pricing applies
  • Data transfer fees apply based on standard S3 rates
  • Amazon VPC endpoint charges apply when using VPC endpoints with access points
  • Access points are Region-specific
  • Each access point is created in the same Region as its S3 bucket
  • Cross-Region access requires separate access points in each Region
  • VPC-specific access points are limited to the VPC’s Region

The following table shows the solutions described in Part 1.

Solution AWS services Security features Cost* Region control
AWS Transfer Family Transfer Family, Amazon S3, API Gateway, and Lambda Managed security, encryption in transit and at rest, IAM integration, and custom authentication $0.30 per hour per protocol, data transfer fees, and storage costs Can deploy to specific AWS Regions, can only transfer files to and from S3 buckets in the same Region
Transfer Family web apps Transfer Family, S3, and CloudFront Browser-based access, IAM Identity Center integration, and S3 Access Grants Pay-per-file operation, CloudFront costs, and storage costs Uses CloudFront (global) for web access, but backend components can be Region-specific
Amazon S3 pre-signed URLs S3 Time-limited URLs, IAM controls for URL generation, and HTTPS S3 request and data transfer fees Can be restricted to specific Regions
Serverless application with Amazon S3 presigned URLs S3, Lambda, and API Gateway Time-limited URLs, HTTPS, IAM controls, customizable authentication Pay per request and minimal infrastructure cost Components can be Region-specific

* Pricing information provided is based on AWS service rates at the time of publication and is intended as an estimation only. Additional costs may be incurred depending on your specific implementation and usage patterns. For the most current and accurate pricing details, please consult the official AWS pricing pages for each service mentioned.

Let’s examine each of the solutions in detail. Part 1 talked about AWS Transfer Family, Transfer Family web apps, and Amazon S3 pre-signed URLs. Here in Part 2, we explain the remaining solutions to help you make the right choice for your use case.

CloudFront signed URLs with Amazon S3

Amazon CloudFront signed URLs combine Amazon S3 storage with the global edge network of CloudFront to deliver files securely with lower latency.

CloudFront edge locations cache content geographically closer to users, which usually reduces latency and gives better performance for users. CloudFront also reduces the number of origin requests to Amazon S3. CloudFront integration with AWS Shield and AWS WAF provides options for additional security layers, helping to protect against DDoS events and unintended requests. You can use custom domains with AWS-provided or your own SSL/TLS certificates managed through AWS Certificate Manager (ACM), helping to facilitate secure connections from users to edge locations.

When a user requests a file, the system generates a signed URL using either a CloudFront key pair or a custom trusted signer (such as Lambda Edge) that includes security parameters such as IP restrictions, time windows, and custom policies. The major difference is the content distribution network (CDN) making performance faster by caching data geographically close to the user downloading it.

The built-in logging and monitoring capabilities of CloudFront provide detailed insights into content access patterns, cache hit ratios, and security events. CloudFront integrates seamlessly with Amazon S3 to support origin access identity (OAI), helping to make sure that the S3 objects can be accessed only through CloudFront and not directly through S3 APIs.

Figure 1: CloudFront signed URLs with Amazon S3 architecture

Figure 1: CloudFront signed URLs with Amazon S3 architecture

Pros

If Amazon S3 pre-signed URLs sound good, but you need higher performance at a global scale, CloudFront signed URLs are the right choice. The AWS global edge network has points of presence (POPs) all over the world, which significantly reduces latency for users and minimizes data transfer costs through caching. This architecture provides substantial cost savings for frequently accessed content, because edge locations serve cached copies without retrieving objects from the S3 origin. The integration with AWS security services offers protection against various threats, including sophisticated distributed denial of service (DDoS) events and web application issues, making it particularly suitable for public-facing file sharing applications. Choose CloudFront instead of S3 if you tend to make the same file available to many people who download it many times, such as in software distribution or documentation distribution.

The solution’s security model provides extensive flexibility in access control implementation. You can define granular permissions through custom policies, implement geo-restriction rules, and enforce IP-based access controls. The ability to use custom TLS certificates and domains maintains brand consistency while helping to facilitate secure communications. The integration with AWS WAF enables advanced request filtering and rate limiting, while detailed access logging and real-time metrics provide visibility into content delivery and security events. The solution’s support for both signed URLs and signed cookies offers flexibility in implementing various access control scenarios. Signed cookies are used when you want to provide access to multiple restricted files. For example, if you need to provide access to many files in a private directory, you can use signed cookies to avoid having to create individual signed URLs for each file. When choosing between CloudFront signed URLs (ideal for individual file access) or signed cookies (better for providing access to multiple files, like a subscriber’s content library), consider your content distribution needs and whether your clients support cookies.

Cons

If you implement CloudFront, you must develop expertise in its configuration options, including robust key management processes and secure key rotation procedures. Self-managed certificates don’t automatically renew. You must track expiration dates and make sure you renew on time, or your users will get warnings and errors when they try to download. ACM can simplify TLS certificate management and automatically renew certificates before they expire. while trusted signer workflows enhance your security posture.

Note: To create signed URLs, you need a signer. A signer is either a trusted key group that you create in CloudFront, or an AWS account that contains a CloudFront key pair.

Misconfigured web caches have many surprising and frustrating effects for users. Understanding and configuring CloudFront cache behavior is key to helping to prevent unintended content exposure or availability issues. You need to add cache invalidation to your publication workflows so that old versions are no longer available from the cache. This might introduce additional costs and operational overhead, especially in scenarios with frequent content changes. If you frequently change the content that you share, if the content is unique to an individual (such as a personalized report), or if the same content isn’t downloaded many times by many people in many locations, you won’t realize much cost savings or reduced latency from CloudFront caching. The additional complexity added by cache configuration might not be justified unless the cache is used a lot.

If you use the CloudFront global content delivery network, your content will be stored in caches in hundreds of locations around the world. ACM will store your TLS certificates for CloudFront (whether ACM is issuing them or you manage them yourself) in the us-east-1 AWS Region. Because CloudFront is a global service, it automatically distributes the certificate from the us-east-1 Region to the Regions associated with your CloudFront distribution. Caching data and keys around the world might not be acceptable if you have data sovereignty requirements to keep your data in one country.

From a cost perspective, while CloudFront can provide savings through caching, the pricing model has other variables to consider. Data transfer costs vary by Region and can be significant for large-scale distributions. If you need custom domain names and custom TLS certificates, that might introduce additional costs. Implementation expertise is needed when dealing with dynamic content or when specific origin request handling is required. CloudFront only delivers via HTTPS and HTTP protocols, so you won’t be able to use it if you require support for other file transfer protocols. CloudFront distributions provide statistics on cache hit-and-miss rates—pay attention to these because low cache hit rates mean that you’re pulling data from the origin frequently, which limits the possible cost savings.

Amazon VPC endpoint service with custom application

Amazon VPC endpoint services, powered by AWS PrivateLink, enable private connectivity between VPCs without requiring internet access, VPN connections, or direct physical connections. This solution creates a highly secure, private network path for file sharing by exposing services through Network Load Balancers (NLB) and allowing other VPCs to access them through interface endpoints. The architecture isolates the file sharing service from the public internet, operating entirely within the AWS private network infrastructure.

The best use cases for this architecture involve sharing data or distributing software around your AWS infrastructure without exposing it to the public internet.

Figure 2: Amazon VPC endpoint service architecture

Figure 2: Amazon VPC endpoint service architecture

The solution, shown in Figure 2, typically involves deploying a custom file sharing application behind an NLB in the service VPC, which is then exposed as an endpoint service. Consumer VPCs create interface endpoints to connect to this service, establishing private connectivity through the AWS backbone network. Traffic remains within the AWS network, is encrypted in transit, and is subject to security controls at both the endpoint and VPC levels. The architecture supports many TCP-based protocols, making it versatile for various file transfer requirements.

This architecture provides secure pathways for data to travel by using multiple layers, including VPC security groups, network access control lists (ACLs), endpoint policies, and the custom application’s authentication mechanisms. The built-in security features of PrivateLink are designed so that only approved AWS principals can create interface endpoints to connect to the service, while detailed VPC flow logs provide network traffic visibility.

Pros

Amazon VPC endpoint services provide complete network isolation and private connectivity that’s inaccessible from the public internet. This reduces the exposure footprint and helps meet security requirements for sensitive data transfer operations. The solution maintains private connectivity across different AWS accounts and Regions while keeping traffic within the AWS network infrastructure.

This solution also provides the most flexible protocol support. Other solutions require you to use HTTPS, AWS API calls (which are HTTPS), or one of the protocols supported by Transfer Family (such as SFTP). If you have software that uses custom protocols, and you need security controls and network isolation, this architecture provides predictable performance through dedicated network paths and supports high throughput requirements without internet bandwidth constraints. The granular control over network security through VPC security groups, network ACLs, and endpoint policies enables organizations to implement defense-in-depth strategies effectively. Additionally, the solution’s integration with AWS Organizations facilitates centralized management and governance across multiple accounts.

Cons

Setting up and maintaining VPC endpoints requires significant expertise in AWS networking, including VPC design, PrivateLink configuration, and network security controls. The initial architecture design must carefully consider IP address management, service quotas, and Regional availability to provide scalability and reliability. Organizations must also develop and maintain the custom file sharing application in addition to the VPC endpoints.

This solution has many components that incur hourly and bandwidth-related charges. Each interface endpoint incurs hourly charges and data processing fees, which can accumulate significantly in multi-VPC or multi-Region deployments. NLBs add another cost component, and you must maintain sufficient capacity for peak loads. The solution also has operational costs because of the need for specialized expertise and ongoing maintenance. Additionally, while the private connectivity model provides superior security, it can make troubleshooting more challenging and might require additional tooling for effective monitoring and diagnostics. The Regional nature of VPC endpoints might necessitate additional architecture for multi-Region deployments, potentially increasing both costs and operational overhead. This solution is most suitable when private network security considerations are the highest priority, and cost considerations are secondary.

Amazon S3 Access Points

Amazon S3 Access Points simplify managing data access at scale for applications using shared data sets on S3. Access points are named network endpoints attached to S3 buckets that streamline managing access to shared datasets. Each access point has its own AWS Identity and Access Management (IAM) policy that controls access to the data, allowing you to create custom access permissions for different applications or user groups accessing the same bucket.

The architecture uses S3 buckets with access points providing dedicated access paths to the data. Each access point has its own hostname (URL) and access policy that works in conjunction with the bucket policy. You can create access points that only allow connections from your Amazon Virtual Private Cloud (Amazon VPC) for private network access to Amazon S3 or create access points with Internet connectivity. You can use this flexibility to implement sophisticated access control patterns while maintaining a single source of truth in S3.

Figure 3: S3 Access Points with VPC endpoints

Figure 3: S3 Access Points with VPC endpoints

Pros

Amazon S3 Access Points simplify permissions management and security to accommodate multiple access patterns and use cases. For example, if an S3 bucket contains data that needs to be accessed by multiple applications, each requiring different levels of access, you can create a dedicated access point for each application with precisely the permissions it needs, rather than managing a long monolithic bucket policy.

You can implement access control workflows, such as restricting access to specific VPCs, encryption, or limit access to specific objects or prefixes. The service requires no new infrastructure management, reducing operational overhead and allowing you to focus on business logic implementation.

Access points provide a way to enforce network controls through VPC-only access points, helping to make sure that data can only be accessed from within your private network. IAM permissions management becomes more granular and straightforward to audit when each application or user group has its own access point with a dedicated policy. You can associate different access points with different network origins.

Another possible use case is when you need to provide temporary access to specific data within a bucket without modifying the bucket policy. You can create a temporary access point with the necessary permissions and delete it when the access is no longer needed.

Cons

Access points add another layer to your Amazon S3 architecture that needs to be managed and monitored. Each access point has its own Amazon Resource Name (ARN) and hostname that applications need to use instead of the bucket name, which might require changes to your application code.

There are limits to the number of access points you can create for each bucket, which might be a constraint for large-scale applications. Access points can only control access to the bucket they’re associated with, not across multiple buckets, so if your application needs to access data across buckets, you’ll need multiple access points.

When implementing this solution, you need to design your access point policies to make sure that they work correctly with your bucket policy. Think of your S3 bucket policy as the primary security framework, while access point policies act as specialized gatekeepers. These two layers of security must work in harmony. The bucket policy takes precedence. For example, if your bucket policy explicitly denies access from specific IP ranges, an access point policy can’t override this restriction. This hierarchical relationship requires strategic planning. Start by defining your broad security boundaries in the bucket policy—perhaps allowing access only from specific VPCs or requiring encryption. Then create your access point policies within these boundaries.

While Amazon S3 Access Points offer powerful flexibility, understanding their boundaries is crucial. Cross-account scenarios, common in large enterprises or partner collaborations, require careful configuration. Imagine you’re working with an external auditing firm that needs temporary access to your financial data stored in S3. Setting up a cross-account access point requires creating the access point in your account, configuring a trust policy to allow the external account, verifying that the bucket policy permits access from the access point, and providing the auditors with the access point ARN and necessary IAM permissions in their account. This process maintains tight control over your data while enabling secure cross-account access.

Some Amazon S3 operations are only controlled at the bucket level and can’t be controlled by access points. Core bucket operations such as configuring versioning, logging, managing lifecycle policies, and setting up cross-Region replication require direct bucket access. For these operations, you need to interact directly with the bucket through the appropriate permissions. This limitation helps make sure that fundamental bucket configurations remain centralized and controlled by bucket owners.

Creating a dedicated IAM role for bucket administration tasks—separate from the roles that interact with data through access points—enhances security and aligns with the principle of least privilege.

Conclusion

In this second part of a two-part post, you’ve learned about multiple solutions for secure file sharing using AWS services and the pros and cons of each. You can find additional options and a full decision matrix in Part 1. The optimal solution depends on your specific organizational requirements, technical capabilities, and budget constraints. You don’t have to choose just one option, you can implement multiple solutions to address different use cases, creating a file sharing strategy that balances security, cost, and operational efficiency.

Additional resources:

If you have feedback about this post, submit comments in the Comments section below.
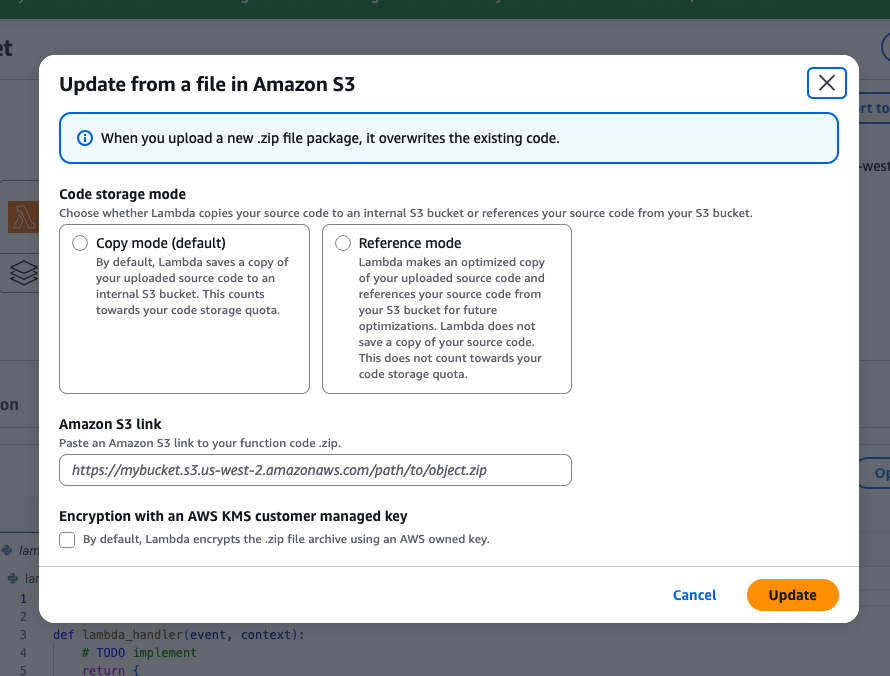
Swapnil Singh

Swapnil Singh

Swapnil is a Senior Solutions Architect for AWS World Wide Public Sector. As a Product Acceleration Solutions Architect at AWS, she currently works with GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices.

Sumit Bhati

Sumit Bhati

Sumit is a Senior Customer Solutions Manager at AWS, specializing in expediting the cloud journey for enterprise customers. Sumit is dedicated to assisting customers through every phase of their cloud adoption, from accelerating migrations to modernizing workloads and facilitating the integration of innovative practices.

Build a multi-Region analytics solution with Amazon Redshift, Amazon S3, and Amazon QuickSight

Post Syndicated from Donatas Kuchalskis original https://aws.amazon.com/blogs/big-data/build-a-multi-region-analytics-solution-with-amazon-redshift-amazon-s3-and-amazon-quicksight/

Organizations increasingly face complex requirements balancing regional data sovereignty with global analytics needs. Regulatory frameworks like GDPR, HIPAA, and local data protection laws often mandate storing data in specific geographic regions, and business operations require global teams to access and analyze this data efficiently.

This post explores how to effectively architect a solution that addresses this specific challenge: enabling comprehensive analytics capabilities for global teams while making sure that your data remains in the AWS Regions required by your compliance framework. We use a variety of AWS services, including Amazon Redshift, Amazon Simple Storage Service (Amazon S3), and Amazon QuickSight.

It’s important to note that this solution focuses primarily on data residency (where data is stored) and not on preventing data from being in transit between Regions. Organizations with strict data transit restrictions might need additional controls beyond what’s covered here. We show how you can configure AWS across Regions to help meet business needs and regulatory requirements simultaneously.

Cross-Region architecture requirements

Before implementing a cross-Region solution, it’s important to understand when this approach is actually necessary. Although single-Region deployments offer simplicity and cost advantages, several specific business and regulatory scenarios warrant a cross-Region approach:

  • Data sovereignty and residency requirements – When regulations like GDPR, HIPAA, or local data sovereignty laws require data to remain in specific geographic boundaries while still enabling global analytics capabilities
  • Global operations with local compliance – When your organization operates globally, but needs to adhere to regional compliance frameworks while maintaining unified analytics
  • Performance optimization for global users – When your organization needs to optimize analytics performance for users in different geographic areas while centralizing data governance
  • Enhanced business continuity – When your analytics capabilities need higher availability and Regional redundancy to support mission-critical business processes

Use case: Financial services analytics with Regional data residency

Consider a financial services company with the following business and regulatory requirements:

  • Data residency requirement – All customer financial data must remain in the Bahrain Region (me-south-1) to comply with local financial regulations.
  • Global analytics capability – The organization’s data science team operates from European offices and needs to access and analyze the financial data without moving it out of its mandated storage Region.
  • Advanced analytics requirements – Business leaders need interactive data exploration and natural language query capabilities to derive insights from financial data.
  • Performance requirement – Specific dashboard queries require subsecond response times for both local executives and the global management team.

This specific combination of requirements can’t be met with a single-Region deployment. Let’s explore how to architect a solution.

Solution overview

The following architecture is designed to address the specific challenge of using QuickSight in one Region while maintaining data in another Region.

As shown in the architecture diagram, data engineers based in Bahrain (me-south-1) work with local data, whereas data engineers in Stockholm (eu-north-1) and analysts in Ireland (eu-west-1) can securely access the same data through Redshift datashares and virtual private cloud (VPC) peering connections. This approach maintains data residency in me-south-1 while enabling global access.

The solution consists of the following key components:

  • Primary data Region (me-south-1):
    • Redshift cluster (primary data repository)
    • S3 buckets for data lake storage
    • Private and public subnets with appropriate security controls
    • Data must remain in this Region for compliance reasons
  • Analytics services Region (eu-west-1):
    • QuickSight deployment
    • Cross-Region VPC peering connection to the primary Region
    • Data access using Redshift datashares (no data replication)
  • Data engineering Region (eu-north-1):
    • Redshift consumer cluster for data engineering workloads
    • Data access using Redshift datashares from me-south-1
    • Makes it possible for data engineering teams in eu-north-1 to access and work with data while maintaining compliance

Before implementing this architecture, evaluate whether:

  • Your requirements actually necessitate a cross-Region approach
  • The performance impact is acceptable for your use case
  • The additional cost is justified by your business requirements

For most analytics workloads, a single-Region architecture remains the recommended approach for simplicity, performance, and cost-effectiveness. Consider cross-Region architectures only when specific business and compliance requirements make them necessary.

Establish cross-Region network connectivity: Amazon Redshift to QuickSight

The foundation of a cross-Region solution is secure, reliable network connectivity. VPC peering provides a straightforward approach for connecting VPCs across Regions. To implement VPC peering in Amazon Virtual Private Cloud (Amazon VPC), complete the following steps:

  1. Create a new VPC in the secondary Region (eu-west-1):
    1. Open the Amazon VPC console in the eu-west-1 Region.
    2. Choose Create VPC.
    3. Set IPv4 CIDR block to 172.32.0.0/16 (verify there is no overlap with the primary Region VPC).
    4. Select Auto-generate to create subnets automatically within this new VPC.
    5. Leave other settings as default and choose Create VPC.

  1. Set up VPC peering:
    1. On the Amazon VPC console, choose Peering connections in the navigation pane and choose Create peering connection.
    2. Select the new eu-west-1 VPC as the requester.
    3. For Select another VPC to peer with, select My account and Another Region.
    4. Choose the primary Region (me-south-1) and enter the VPC ID.
    5. Choose Create peering connection.

  1. Accept the VPC peering connection:
    1. Switch to the primary Region on the Amazon VPC console.
    2. Choose Peering connections in the navigation pane and select the pending connection.
    3. On the Actions dropdown menu, choose Accept request.

  1. Update the route tables:
    1. On the  secondary Region Amazon VPC console, choose Route tables in the navigation pane.
    2. Choose the route table for the new VPC.
    3. Choose Edit routes and add a new route:
      • Destination: Primary Region VPC CIDR (e.g., 172.31.0.0/16).
      • Target: Choose the peering connection.
    4. On the primary Region Amazon VPC console, repeat the process, adding a route to the secondary Region VPC CIDR (172.32.0.0/16) using the peering connection.

  1. Configure security groups:
    1. On the secondary Region Amazon VPC console, choose Security groups in the navigation pane and create a new security group.
    2. Add an outbound rule:
      • Type: Custom TCP
      • Port range: 5439
      • Destination: Primary Region VPC CIDR

    3. On the primary Region Amazon VPC console, locate the Redshift cluster’s security group.
    4. Add an inbound rule:
      • Type: Custom TCP
      • Port range: 5439
      • Source: Secondary Region VPC CIDR

  1. Configure DNS settings:
    1. On the Amazon VPC console for both Regions, choose Your VPCs in the navigation pane.
    2. Select each VPC, and on the Actions dropdown menu, choose Edit DNS hostnames.
    3. Select Enable DNS resolution and Enable DNS hostnames.

Implement cross-Region data sharing

Rather than replicating data, which could create compliance issues, you can use Redshift datashares to provide secure, read-only access to data across Regions. Complete the following steps to set up your datashares:

  1. Create producer datashares in the primary Region:
    1. On the Amazon Redshift console, choose Query editor v2 in the navigation pane to connect to your primary Region Redshift cluster (me-south-1).
    2. Run the following commands:
      -- In Primary Region Redshift
      
      CREATE DATASHARE datashare_1;
      ALTER DATASHARE datashare_1 ADD SCHEMA analytics;
      ALTER DATASHARE datashare_1 ADD TABLE analytics.customers;
      ALTER DATASHARE datashare_1 ADD TABLE analytics.transactions;
      
      -- Grant usage permissions
      	
      GRANT USAGE ON DATASHARE datashare_1 TO ACCOUNT '123456789012';

  1. Create a consumer database in the secondary Region:
  2. Connect to your secondary Region Redshift cluster (eu-west-1) using the query editor and run the following commands:
    -- In Secondary Region Redshift
    
    CREATE DATABASE consumer_db FROM DATASHARE datashare_1 OF ACCOUNT '123456789012'REGION 'me-south-1';
  3. Verify the datashare configuration with the following code:
    -- In Secondary Region Redshift
    
    SELECT * FROM SVV_DATASHARE_CONSUMERS;
    SELECT * FROM SVV_DATASHARE_OBJECTS; 

This approach maintains data residency in the primary Region while enabling analytics access from another Region, addressing the core challenge of Regional service limitations. For our financial services company example, this makes sure that customer financial data remains in Bahrain (me-south-1) while making it securely accessible to the data science team in Europe (eu-west-1).

Configure QuickSight in the analytics Region

With network connectivity and data sharing established, complete the following steps to configure QuickSight to securely access the Redshift data:

  1. Set up a QuickSight VPC connection:
    1. Open the QuickSight console in the secondary Region.
    2. Choose Manage QuickSight, VPC connections, and Add VPC connection.
    3. Configure the connection:
      • Name: Enter a name (for example, Cross-Region-Connection).
      • VPC: Choose the secondary Region VPC.
      • Subnet: Choose the automatically created subnets.
      • Security group: Choose the security group created for cross-Region access.

  1. Add a QuickSight IP range to the data source security group:
    1. Open the Amazon Elastic Compute Cloud (Amazon EC2) console in the primary Region.
    2. Choose Security groups in the navigation pane and find the security group for your data source.
    3. Edit the inbound rules.
    4. Add a new rule:
      • Type: HTTPS (443)
      • Protocol: TCP
      • Port range: 443
      • Source: QuickSight IP range for the secondary Region (for example, 52.210.255.224/27 for eu-west-1).

QuickSight IP ranges can change over time. Refer to AWS Regions, websites, IP address ranges, and endpoints for current IP ranges.

  1. Create a QuickSight data source:
    1. On the QuickSight console, choose Datasets in the navigation pane.
    2. Choose New dataset, then choose Redshift.
    3. Configure the connection:
      • Data source name: Enter a descriptive name.
      • Connection type: Choose the VPC connection.
      • Database server: Enter the Redshift cluster endpoint from the primary Region.
      • Port: 5439
      • Database name: Enter the consumer database name.
      • Username and Password: Enter credentials (consider using AWS Secrets Manager).
    4. Choose Validate connection to test.
    5. Choose Create data source.

  1. Verify the connection and create datasets:
    1. Choose the schema and tables from the consumer database.
    2. Configure appropriate refresh schedules.
    3. Create calculations and visualizations as needed.

Performance considerations for cross-Region analytics

When implementing a cross-Region analytics architecture, be aware of the following performance implications:

  • Query performance impact – Cross-Region queries can experience higher latency than single-Region queries. To mitigate this, consider the following:
    • Use SPICE for QuickSight – Import frequently-used datasets into SPICE (Super-fast, Parallel, In-memory Calculation Engine) to help avoid repeated cross-Region queries. SPICE is the QuickSight in-memory engine that enables fast, interactive visualizations by precomputing and storing datasets locally in the QuickSight Region.
    • Implement efficient query patterns – Minimize the amount of data transferred between Regions.
    • Use appropriate caching – Enable result caching where possible.
    • Monitoring cross-Region performance – Implement monitoring to identify and address performance issues:
      • Set up Amazon CloudWatch metrics to track cross-Region query performance
      • Create dashboards to visualize latency trends
      • Establish performance baselines and alerts for degradation

Security considerations

Maintaining security in a cross-Region architecture requires additional attention:

  • Network security:
    • Limit VPC peering connections to only necessary VPCs
    • Implement restrictive security groups that allow only required traffic
    • Consider using VPC endpoints for service access when possible
  • Data access controls:
    • Use AWS Identity and Access Management (IAM) policies consistently across Regions
    • Implement fine-grained access controls in Redshift datashares
    • Enable audit logging in relevant Regions
  • Compliance monitoring:
    • Implement AWS CloudTrail in all Regions
    • Create centralized logging for cross-Region activities
    • Regularly review cross-Region access patterns

Cost implications

Before implementing a cross-Region architecture, consider these cost factors:

  • Data transfer costs – Data transfer between Regions incurs charges
  • Additional infrastructure – You might need Redshift clusters in multiple Regions
  • VPC peering costs – Data transfer costs are associated with VPC peering
  • Operational overhead – Managing multi-Region deployments requires additional resources
  • Workload-based sizing – You should size each Regional Redshift cluster according to the specific workloads it will handle

Conclusion

The cross-Region architecture described in this post addresses specific challenges related to Regional compliance requirements and global analytics needs, particularly in the following scenarios:

  • Your data must remain in a specific Region for compliance reasons
  • You have teams in different Regions who need to access and analyze this data
  • Different user groups have distinct workload requirements

The datasharing capabilities of Amazon Redshift and Regional storage options in Amazon S3 are key enablers of this solution, allowing data to remain in the required Region while still being accessible for analytics across Regions. However, it’s worth emphasizing that this architecture supports data storage in specific Regions but doesn’t prevent data from traveling between Regions during processing. Organizations concerned about data transit restrictions should evaluate additional controls to address those specific requirements. Combined with secure VPC peering connections and QuickSight visualizations, this architecture creates a complete solution that satisfies both compliance requirements and business needs.

For our financial services example, this architecture successfully enables the company to keep its customer financial data in Bahrain while providing seamless analytics capabilities to the European data science team and delivering interactive dashboards to global business leaders.

For more information, refer to Building a Cloud Security Posture Dashboard with Amazon QuickSight. For hands-on experience, explore the Amazon QuickSight Workshops. Visit the Amazon Redshift console or Amazon QuickSight console to start building your first dashboard, and explore our AWS Big Data Blog for more customer success stories and implementation patterns

Try out this solution for your own use case, and share your thoughts in the comments.


About the Authors

Donatas Kuchalskis is a Cloud Operations Architect at AWS, based in London, focusing on Financial Services customers in the UK. He helps customers optimize their AWS environments for cost, security, and resiliency while providing strategic cloud guidance. Prior to this role, he served as a Prototyping Architect specializing in Big Data and as a Specialist Solutions Architect for Retail. Before joining AWS, Donatas spent 6 years as a technical consultant in the retail sector.

Jumana Nagaria is a Prototyping Architect at AWS. She builds innovative prototypes with customers to solve their business challenges. She is passionate about cloud computing and data analytics. Outside of work, Jumana enjoys travelling, reading, painting, and spending quality time with friends and family.

Scalable analytics and centralized governance for Apache Iceberg tables using Amazon S3 Tables and Amazon Redshift

Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/scalable-analytics-and-centralized-governance-for-apache-iceberg-tables-using-amazon-s3-tables-and-amazon-redshift/

Amazon Redshift supports querying data stored in Apache Iceberg tables managed by Amazon S3 Tables, which we previously covered as part of getting started blog post. While this blog post helps you to get started using Amazon Redshift with Amazon S3 Tables, there are additional steps you need to consider when working with your data in production environments, including who has access to your data and with what level of permissions.

In this post, we’ll build on the first post in this series to show you how to set up an Apache Iceberg data lake catalog using Amazon S3 Tables and provide different levels of access control to your data. Through this example, you’ll set up fine-grained access controls for multiple users and see how this works using Amazon Redshift. We’ll also review an example with simultaneously using data that resides both in Amazon Redshift and Amazon S3 Tables, enabling a unified analytics experience.

Solution overview

In this solution, we show how to query a dataset stored in Amazon S3 Tables for further analysis using data managed in Amazon Redshift. Specifically, we go through the steps shown in the following figure to load a dataset into Amazon S3 Tables, grant appropriate permissions, and finally execute queries to analyze our dataset for trends and insights.

Solution Architecture

In this post, you walk through the following steps:

  1. Creating an Amazon S3 Table bucket: In AWS Management Console for Amazon S3, create an Amazon S3 Table bucket and integrate with other AWS analytics services
  2. Creating an S3 Table and loading data: Run spark SQL in Amazon EMR to create a namespace and an S3 Table and load diabetic patients’ visit data
  3. Granting permissions: Granting fine-grained access controls in AWS Lake Formation
  4. Running SQL analytics: Querying S3 Tables using the auto mounted S3 Table catalog.

This post uses data from a healthcare use case to analyze information about diabetic patients and identify the frequency of age groups admitted to the hospital. You’ll use the preceding steps to perform this analysis.

Prerequisites

To begin, you need to add an Amazon Redshift service-linked role—AWSServiceRoleForRedshift—as a read-only administrator in Lake Formation. You can run following AWS Command Line Interface (AWS CLI) command to add the role.

Replace <account_number> with your account number and replace <region> with the AWS Region that you are using. You can run this command from AWS CloudShell or through AWS CLI configured in your environment.

aws lakeformation put-data-lake-settings \
        --region <region> \
        --data-lake-settings \
 '{
   "DataLakeAdmins": [{"DataLakePrincipalIdentifier":"arn:aws:iam::<account_number>:role/Admin"}],
   "ReadOnlyAdmins":[{"DataLakePrincipalIdentifier":"arn:aws:iam:: <account_number>:role/aws-service-role/redshift.amazonaws.com/AWSServiceRoleForRedshift"}],
   "CreateDatabaseDefaultPermissions":[],
   "CreateTableDefaultPermissions":[],
   "Parameters":{"CROSS_ACCOUNT_VERSION":"4","SET_CONTEXT":"TRUE"}
  }'

You also need to create or use an existing Amazon Elastic Compute Cloud (Amazon EC2) key pair that will be used for SSH connections to cluster instances. For more information, see Amazon EC2 key pairs.

The examples in this post require the following AWS services and features:

The CloudFormation template that follows creates the following resources:

  • An Amazon EMR 7.6.0 cluster with Apache Iceberg packages
  • An Amazon Redshift Serverless instance
  • An AWS Identity and Access Management (IAM) instance profile, service role, and security groups
  • IAM roles with required policies
  • Two IAM users: nurse and analyst

Download the CloudFormation template, or you can use the Launch Stack button to automatically download it to your AWS environment. Note that network routes are directed to 255.255.255.255/32 for security reasons. Replace the routes with your organization’s IP addresses. Also enter your IP or VPN range for Jupyter Notebook access in the SourceCidrForNotebook parameter in CloudFormation.

Launch CloudFormation Stack

Download the diabetic encounters and patient datasets and upload it into your S3 bucket. These files are from a publicly available open dataset.

This sample dataset is used to highlight this use case, the techniques covered can be adapted to your workflows. The following are more details about this dataset:

diabetic_encounters_s3.csv: Contains information about patient visits for diabetic treatment.

  • encounter_id: Unique number to refer to an encounter with a patient who has diabetes.
  • patient_nbr: Unique number to identify a patient.
  • num_procedures: Number of medical procedures administered.
  • num_medications: Number of medications provided during the visit
  • insulin: Insulin level observed. Valid values are steady, up, and no.
  • time_in_hospital: Duration of time in hospital in days.
  • readmitted: Readmitted to hospital within 30 days or after 30 days.

diabetic_patients_rs.csv: Contains patient information such as age group, gender, race, and number of visits.

  • patient_nbr: Unique number to identify a patient
  • race: Patient’s race
  • gender: Patient’s gender
  • age_grp: Patient’s age group. Valid values are 0-10, 10-20, 20-30, and so on
  • number_outpatient: Number of outpatient visits
  • number_emergency: Number of emergency room visits
  • number_inpatient: Number of inpatient visits

Now that you’ve set up the prerequisites, you’re ready to connect Amazon Redshift to query Apache Iceberg data stored in Amazon S3 Tables.

Create an S3 Table bucket

Before you can use Amazon Redshift to query the data in an Amazon S3 Table, you must create an Amazon S3 Table.

  1. Sign in to the AWS Management Console and go to Amazon S3.
  2. Go to Amazon S3 Table buckets. This is an option in the Amazon S3 console.
  3. In the Table buckets view, there’s a section that describes Integration with AWS analytics services. Choose Enable Integration if you haven’t previously set this up. This sets up the integration with AWS analytics services, including Amazon Redshift, Amazon EMR, and Amazon Athena.
    Enable Integration
  4. Wait a few seconds for the status to change to Enabled.
    Integration Enabled
  5. Choose Create table bucket and enter a bucket name. You can use any name that follows the naming conventions. In this example, we used the bucket name patient-encounter. When you’re finished, choose Create table bucket.Create Table Bucket
  6. After the S3 Table bucket is created, you’ll be redirected to the Table buckets list. Copy the Amazon Resource Name (ARN) of the table bucket you just created to use in the next section.Table Bucket List

Now that your S3 Table bucket is set up, you can load data.

Create S3 Table and load data

The CloudFormation template in the prerequisites created an Apache Spark cluster using Amazon EMR. You’ll use the Amazon EMR cluster to load data into Amazon S3 Tables.

  1. Connect to the Apache Spark primary node using SSH or through Jupyter Notebooks. Note that an Amazon EMR cluster was launched when you deployed the CloudFormation template.
  2. Enter the following command to launch the Spark shell and initialize a Spark session for Iceberg that connects to your S3 Table bucket. Replace <Region>, <accountID> and <bucketname><bucket arn> with the information your region, account and bucket name.
    spark-shell \
      --packages "org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.4.1,software.amazon.awssdk:bundle:2.20.160,software.amazon.awssdk:url-connection-client:2.20.160" \
      --master "local[*]" \
      --conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
      --conf "spark.sql.defaultCatalog=spark_catalog" \
       --conf "spark.sql.catalog.spark_catalog=org.apache.iceberg.spark.SparkCatalog" \
      --conf "spark.sql.catalog.spark_catalog.type=rest" \
      --conf "spark.sql.catalog.spark_catalog.uri=https://s3tables.<Region>.amazonaws.com/iceberg" \
      --conf "spark.sql.catalog.spark_catalog.warehouse=arn:aws:s3tables:<Region>:<accountID>:bucket/<bucketname>" \
      --conf "spark.sql.catalog.spark_catalog.rest.sigv4-enabled=true" \
      --conf "spark.sql.catalog.spark_catalog.rest.signing-name=s3tables" \
      --conf "spark.sql.catalog.spark_catalog.rest.signing-region=<Region>" \
      --conf "spark.sql.catalog.spark_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO" \
      --conf "spark.hadoop.fs.s3a.aws.credentials.provider=org.apache.hadoop.fs.s3a.SimpleAWSCredentialProvider" \
      --conf "spark.sql.catalog.spark_catalog.rest-metrics-reporting-enabled=false"               

See Accessing Amazon S3 Tables with Amazon EMR for upgrades to software.amazon.s3tables package versions.

  1. Next, create a namespace that will link your S3 Table bucket with your Amazon Redshift Serverless workgroup. We chose encounters as the namespace for this example, but you can use a different name. Use the following SparkSQL command:
    spark.sql("CREATE NAMESPACE IF NOT EXISTS s3tablesbucket.encounters")

  2. Create an Apache Iceberg table with name diabetic_encounters.
    spark.sql( 
    """ CREATE TABLE IF NOT EXISTS s3tablesbucket.encounters.`diabetic_encounters` ( 
    encounter_id INT, 
    patient_nbr INT,
    num_procedures INT,
    num_medications INT,
    insulin STRING,
    time_in_hospital INT,
    readmitted STRING 
    ) 
    USING iceberg """
    )

  3. Load csv into the S3 Table encounters.diabetic_encounters. Replace <diabetic_encounters_s3.csv file location> with the Amazon S3 file path of the diabetic_encounters_s3.csv file you uploaded earlier.
    val df = spark.read.format("csv").option("header", "true").option("inferSchema", "true").load("<diabetic_encounters_s3.csv file location> ")
    
    df.writeTo("s3tablesbucket.encounters.diabetic_encounters").using("Iceberg").tableProperty ("format-version", "2").createOrReplace()

  4. Query the data to validate it using Spark shell.
    spark.sql(""" SELECT * FROM s3tablesbucket.encounters.diabetic_encounters """).show()

Grant permissions

In this section, you grant fine-grained access control to the two IAM users created as part of the prerequisites.

  • nurse: Grant access to all columns in the diabetic_encounters table
  • analyst: Grant access to only {encounter_id, patient_nbr, readmitted} columns

First, grant access to the diabetic_encounters table for nurse user.

  1. In AWS Lake Formation, Choose Data Permissions.
  2. On the Grant Permissions page, under Principals, select IAM users and roles.
  3. Select the IAM user nurse.
  4. For Catalogs, select <accoundID>:s3tablescatalog/patient-encounter.
  5. For Databases, select encounterGrant Database Permissions
  6. Scroll down. For Tables, select diabetic_encounters.
  7. For Table permissions, select Select.
  8. For Data permissions, select All data access.Grant Table Permissions
  9. Choose Grant. This will grant select access on all the columns in diabetic_encounters to the nurse

Now grant access to the diabetic_encounters table for the analyst user.

  1. Repeat the same steps that you followed for nurse user up to step 7 in the previous section.
  2. For Data permissions, select Column-based access. Select Include columns and select the encounter_id, patient_nbr, and readmitted columns
    Grant Column Permissions
  3. Choose Grant. This will grant select access on the encounter_id, patient_nbr, and readmitted columns in diabetic_encounters to the analyst

Run SQL analytics

In this section, you will access the data in the diabetic_encounters S3 Table using nurse and analyst to learn how fine-grain access control works. You will also combine data from the S3 Table data with a local table in Amazon Redshift using a single query.

  1. In the Amazon Redshift Query Editor V2, connect to serverless:rs-demo-wg, an Amazon Redshift Serverless instance created by the CloudFormation template.
  2. Select Database user name and password as the connection method and connect using super user awsuser. Provide the password you gave as an input parameter to the CloudFormation stack.Database Connection
  3. Run the following commands to create the IAM users nurse and analyst in Amazon Redshift.
    CREATE USER IAM:nurse password disable;
    CREATE USER IAM:analyst password disable;

  4. Amazon Redshift automatically mounts the Data Catalog as an external database named awsdatacatalog to simplify accessing your tables in Data Catalog. You can grant usage access to this database for the IAM users:
    GRANT USAGE ON DATABASE awsdatacatalog to "IAM:nurse";
    GRANT USAGE ON DATABASE awsdatacatalog to "IAM:analyst";

For the next steps, you must first sign in to the AWS Console as the nurse IAM user. You can find the IAM user’s password in the AWS Secrets Manager console and retrieving the value from the secret ending with iam-users-credentials. See Get a secret value using the AWS console for more information.

  1. After you’ve signed in to the console, navigate to the Amazon Redshift Query Editor V2.
  2. Sign in to your Amazon Redshift cluster using the IAM:nurse. You can do this by connecting to serverless:rs-demo-wg as Federated user. This applies the permission provided in Lake Formation for accessing your data in Amazon S3 Tables:
    Federated Connection
  3. Run following SQL to query S3 Table diabetic_encounters.
    SELECT * FROM patient-encounter@s3tablescatalog"."encounters"."diabetic_encounters";

This returns all the data in the S3 Table for diabetic_encounters across every column in the table, as shown in the following figure:

Diabetic Encounters Output

Recall that you also created an IAM user called analyst that only has access to the encounter_id, patient_nbr, and readmitted columns. Let’s verify that analyst user can only access those columns.

  1. Sign in to the AWS console as the analyst IAM user and open the Amazon Redshift Query Editor v2 using the same steps as above. Run the same query as before:
    SELECT * FROM patient-encounter@s3tablescatalog"."encounters"."diabetic_encounters";
    

This time, you should only the encounter_id, patient_nbr, and readmitted columns:

Diabetic Encounters Output restricted

Now that you’ve seen how you can access data in Amazon S3 Tables from Amazon Redshift while setting the levels of access required for your users, let’s see how we can join data in S3 Tables to tables that already exist in Amazon Redshift.

Combine data from an S3 Table and a local table in Amazon Redshift

For this section, you’ll load data into your local Amazon Redshift cluster. After this is complete, you can analyze the datasets in both Amazon Redshift and S3 Tables.

  1. First, as the analytics federated user, sign in to your Amazon Redshift cluster using Amazon Redshift Query Editor v2.
  2. Use the following SQL command to create a table that contains patient information.:
    CREATE TABLE public.patient_info (
        patient_nbr integer ENCODE az64,
        race character varying(256) ENCODE lzo,
        gender character varying(256) ENCODE lzo,
        age_grp character varying(256) ENCODE lzo,
        number_outpatient integer ENCODE az64,
        number_emergency integer ENCODE az64,
        number_inpatient integer ENCODE az64);

  3. Copy patient information from the file csv that’s stored in your Amazon S3 object bucket. Replace <diabetic_patients_rs.csv file S3 location> with the location of the file in your S3 bucket.
    COPY dev.public.patient_info FROM 's3://<diabetic_patients_rs.csv file S3 location>' 
    IAM_ROLE default 
    FORMAT AS CSV DELIMITER ',' 
    IGNOREHEADER 1;

  4. Use the following query to review the sample data to verify that the command was successful. This will show information from 10 patients, as shown in the following figure.
    SELECT * FROM public.patient_info limit 10;

    Patient Information

  5. Now combine data from the Amazon S3 Table diabetic_encounters and the Amazon Redshift patient_info. In this example, the query fetches information about what age group was most frequently readmitted to the hospital within 30 days of an initial hospital visit:
    SELECT
        age_grp,
        count(*) readmission_count
    FROM
        "patient-encounter@s3tablescatalog"."encounters"."diabetic_encounters" a
    JOIN public.patient_info b ON b.patient_nbr = a.patient_nbr
    WHERE
        a.readmitted='<30'
    GROUP BY age_grp
    ORDER BY readmission_count DESC
    LIMIT 1;

This query returns results showing an age group and the number of re-admissions, as shown in the following figure.

Redamissions Output

Cleanup

To clean up your resources, delete the stack you deployed using AWS CloudFormation. For instructions, see Deleting a stack on the AWS CloudFormation console.

Conclusion

In this post, you walked through an end-to-end process for setting up security and governance controls for Apache Iceberg data stored in Amazon S3 Tables and accessing it from Amazon Redshift. This includes creating S3 Tables, loading data into them, registering the tables in a data lake catalog, setting up access controls, and querying the data using Amazon Redshift. You also learned how to combine data from Amazon S3 Tables and local Amazon Redshift tables stored in Redshift Managed Storage in a single query, enabling a seamless, unified analytics experience. Try out these features and see Working with Amazon S3 Tables and table buckets for more details. We welcome your feedback in the comments section.


About the Authors

Satesh SontiSatesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

JonathanJonathan Katz is a Principal Product Manager – Technical on the Amazon Redshift team and is based in New York. He is a Core Team member of the open source PostgreSQL project and an active open source contributor, including PostgreSQL and the pgvector project.

How to use AWS Transfer Family and GuardDuty for malware protection

Post Syndicated from James Abbott original https://aws.amazon.com/blogs/security/how-to-use-aws-transfer-family-and-guardduty-for-malware-protection/

Organizations often need to securely share files with external parties over the internet. Allowing public access to a file transfer server exposes the organization to potential threats, such as malware-infected files uploaded by threat actors or inadvertently by genuine users. To mitigate this risk, companies can take steps to help make sure that files received through public channels are scanned for malware before processing.

This post demonstrates how to use AWS Transfer Family and Amazon GuardDuty to scan files uploaded through a secure FTP (SFTP) server for malware as part of an overall transfer workflow. For readers who might have read an earlier blog post on this topic, the key difference is that this solution is fully managed and doesn’t require the deployment of compute resources. GuardDuty automatically updates malware signatures every 15 minutes instead of using a container image for scanning, avoiding the need for manual patching to keep the signatures up to date.

Prerequisites

To deploy the solution in this post, you will need:

  • An AWS account: You need access to AWS to deploy this solution. If you don’t have an account that you can use, see Start building on AWS today.
  • AWS CLI: Install and configure the AWS Command Line Interface (AWS CLI) to be authenticated to your AWS account. Set up the environment variables for your AWS account using the access token and secret access key for your environment.
  • Git: You will use Git to pull down the example code from GitHub.
  • Terraform: You’ll use Terraform to run the automation. Follow the Terraform installation instructions to download and set up Terraform.

Solution overview

This solution uses Transfer Family and GuardDuty. Transfer Family provides a secure file transfer service that you can use to set up an SFTP server, and GuardDuty is an intelligent threat detection service. GuardDuty monitors for malicious activity and anomalous behavior to protect AWS accounts, workloads, and data. At a high level, the solution uses the following steps:

  • A user uploads a file through a Transfer Family SFTP server.
  • A Transfer Family managed workflow invokes AWS Lambda to execute an AWS Step Functions workflow.
    • The workflow begins only after a successful file upload.
    • Partial uploads to the SFTP server will invoke an error handling Lambda function to report a partial upload error.
  • A step function state machine invokes a Lambda function to move uploaded files to an Amazon Simple Storage Service (Amazon S3) bucket for processing and then starts scanning using GuardDuty.
  • The GuardDuty scan result is sent as a callback to the step function.
  • Infected files are moved or cleaned.
  • The workflow sends the user the results through an Amazon Simple Notification Service (Amazon SNS) topic. This can be a notification of an error or malicious upload during the scan or notification of a successful upload and a clean scan for further processing.

Solution architecture and walkthrough

The solution uses GuardDuty Malware Protection for S3 to scan newly uploaded objects to the S3 bucket. You can use this feature of GuardDuty to set up a malware protection plan for an S3 bucket at the bucket level or to watch for specific object prefixes.

Figure 1: Solution architecture

Figure 1: Solution architecture

The following steps (shown in Figure 1) describe the workflow for this solution starting from the point the file is uploaded until it’s scanned and marked as safe or as infected, leading to subsequent steps that can be customized based on your use case.

  1. A file is uploaded using the SFTP protocol through Transfer Family.
  2. If the file is successfully uploaded, Transfer Family uploads the file to the S3 bucket called Unscanned and the Managed Workflow Complete workflow is triggered. This is the workflow used to handle successful uploads and invokes the Step Function Invoker Lambda function.
  3. The Step Function Invoker starts the state machine and kicks off the first step in the process by invoking the GuardDuty – Scan Lambda function.
  4. The GuardDuty – Scan function moves the file to the Processing bucket. This is the bucket from which the files will be scanned.
  5. When an object upload activity is detected, GuardDuty automatically scans the object. In this implementation, a malware protection plan is created for the Processing bucket.
  6. When a scan completes, GuardDuty publishes the scan result to Amazon EventBridge.
  7. An EventBridge rule has been created to invoke a Lambda Callback function whenever a scan event has completed. EventBridge will invoke the function with an event that contains the scan results. See Monitoring S3 object scans with Amazon EventBridge for an example.
  8. The Lambda Callback function notifies the GuardDuty – Scan task using the callback task integration pattern. The results of the GuardDuty scan are returned to the GuardDuty – Scan function and these results are passed to the Move File task.
  9. If the result is a clean scan with no threats detected, the Move File task will place the file in the Clean S3 bucket, indicating that the file is successfully scanned and safe for further processing.
  10. At this point, the Move File function publishes a notification to the Success SNS topic to notify the subscribers.
  11. If the result indicates that the file is malicious, the Move File function will instead move the file to the Quarantine S3 bucket for further investigation. The function will also delete the file from the Processing bucket and publish a notification in the Error topic in SNS to notify the user of a potential malicious file being uploaded.
  12. If the file upload is unsuccessful and the file isn’t fully uploaded, then Transfer Family will trigger the Managed Workflow Partial workflow.
  13. Managed Workflow Partial is an error handling workflow and invokes the Error Publisher function, which is used for reporting errors that occur anywhere in the workflow.
  14. The Error Publisher function identifies the type of error—whether it’s because of the partial upload or an issue elsewhere in the workflow—and sets the error status accordingly. It will then publish an error message to Error Topic in SNS.
  15. The GuardDuty – Scan task has a timeout to make sure that an event is published to Error Topic to prompt a manual intervention to investigate further if the file isn’t successfully scanned. If the GuardDuty – Scan task fails, the Error clean up Lambda function is invoked.

Finally, there’s an S3 Lifecycle policy attached to the Processing bucket. This is to make sure that no file is left in the Processing bucket for more than one day.

Code repository

The GitHub AWS-samples repository has a sample implementation developed using Terraform and Python-based Lambda functions to implement this solution. The same solution can also be implemented using AWS CloudFormation. The code has the components needed to deploy the entire workflow to demonstrate the abilities of Transfer Family and the GuardDuty malware protection plan.

Install the solution

Use the following steps to deploy this solution to your test environment.

  1. Clone the repository to your working directory using Git.
  2. Navigate to the root directory of your cloned project directory.
  3. Update the terraform locals.tf file with the values of your choice for the S3 bucket names, SFTP server names, and other variables.
  4. Run terraform plan.
  5. If everything looks good, run a terraform apply and enter yes to create the resources.

Clean up

After testing and exploring the solution, it’s important to clean up the resources you created to avoid incurring unnecessary costs. To delete the resources created by this solution, navigate to the root directory of your cloned project and run the following command:

terraform destroy

This command will remove the resources created by Terraform, including the SFTP server, S3 buckets, Lambda functions, and other components. Confirm the deletion by entering yes when prompted.

Conclusion

By using the approach outlined in the post, you can make sure that the files received over SFTP and uploaded to your S3 bucket are scanned for threats and are safe for further processing. The solution reduces the exposure surface by making sure that public uploads are scanned in a safe environment before they’re sent to other components of your system.

If you have feedback about this post, submit comments in the Comments section below.
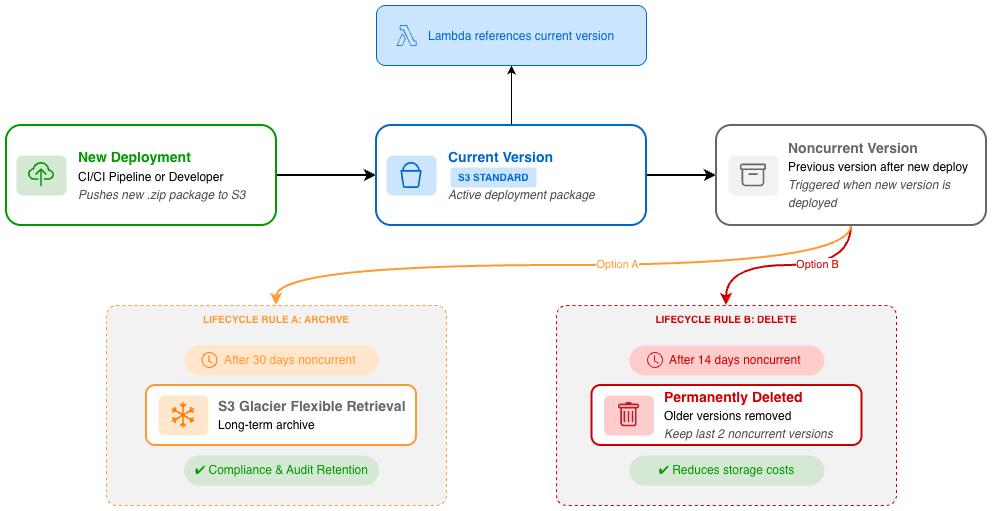
James Abbott

James Abbott

James is a Principal Solutions Architect at AWS, working in Global Financial Services. When not in the office he enjoys mountain biking in North Carolina.

Santhosh Srinivasan

Santhosh Srinivasan

Santhosh is a Sr. Cloud Application Architect with the Professional Services team at AWS. He specializes in building and modernizing large scale enterprise applications in the cloud with a focus on the financial services industry.

Suhas Pasricha

Suhas Pasricha

Suhas is a Cloud Infrastructure Architect in the AWS Professional Services team. He has a background in web development and infrastructure automation. At Amazon, he has been helping customers set up and operate an enterprise-wide landing zone and cloud environment. In his spare time, he likes to read and play video games.

Amazon SageMaker Lakehouse now supports attribute-based access control

Post Syndicated from Sandeep Adwankar original https://aws.amazon.com/blogs/big-data/amazon-sagemaker-lakehouse-now-supports-attribute-based-access-control/

Amazon SageMaker Lakehouse now supports attribute-based access control (ABAC) with AWS Lake Formation, using AWS Identity and Access Management (IAM) principals and session tags to simplify data access, grant creation, and maintenance. With ABAC, you can manage business attributes associated with user identities and enable organizations to create dynamic access control policies that adapt to the specific context.

SageMaker Lakehouse is a unified, open, and secure data lakehouse that now supports ABAC to provide unified access to general purpose Amazon S3 buckets, Amazon S3 Tables, Amazon Redshift data warehouses, and data sources such as Amazon DynamoDB or PostgreSQL. You can then query, analyze, and join the data using Redshift, Amazon AthenaAmazon EMR, and AWS Glue. You can secure and centrally manage your data in the lakehouse by defining fine-grained permissions with Lake Formation that are consistently applied across all analytics and machine learning(ML) tools and engines. In addition to its support for role-based and tag-based access control, Lake Formation extends support to attribute-based access to simplify data access management for SageMaker Lakehouse, with the following benefits:

  • Flexibility – ABAC policies are flexible and can be updated to meet changing business needs. Instead of creating new rigid roles, ABAC systems allow access rules to be modified by simply changing user or resource attributes.
  • Efficiency – Managing a smaller number of roles and policies is more straightforward than managing a large number of roles, reducing administrative overhead.
  • Scalability – ABAC systems are more scalable for larger enterprises because they can handle a large number of users and resources without requiring a large number of roles.

Attribute-based access control overview

Previously, within SageMaker Lakehouse, Lake Formation granted access to resources based on the identity of a requesting user. Our customers were requesting the capability to express the full complexity required for access control rules in organizations. ABAC allows for more flexible and nuanced access policies that can better reflect real-world needs. Organizations can now grant permissions on a resource based on user attribute and is context-driven. This allows administrators to grant permissions on a resource with conditions that specify user attribute keys and values. IAM principals with matching IAM or session tag key-value pairs will gain access to the resource.

Instead of creating a separate role for each team member’s access to a specific project, you can set up ABAC policies to grant access based on attributes like membership and user role, reducing the number of roles required. For instance, without ABAC, a company with an account manager role that covers five different geographical territories needs to create five different IAM roles and grant data access for only the specific territory for which the IAM role is meant. With ABAC, they can simply add those territory attributes as keys/values to the principal tag and provide data access grants based on those attributes. If the value of the attribute for a user changes, access to the dataset will automatically be invalidated.

With ABAC, you can use attributes such as department or country and use IAM or sessions tags to determine access to data, making it more straightforward to create and maintain data access grants. Administrators can define fine-grained access permissions with ABAC to limit access to databases, tables, rows, columns, or table cells.

In this post, we demonstrate how to get started with ABAC in SageMaker Lakehouse and use with various analytics services.

Solution overview

To illustrate the solution, we are going to consider a fictional company called Example Retail Corp. Example Retail’s leadership is interested in analyzing sales data in Amazon S3 to determine in-demand products, understand customer behavior, and identify trends, for better decision-making and increased profitability. The sales department sets up a team for sales analysis with the following data access requirements:

  • All data analysts in the Sales department in the US get access to only sales-specific data in only US regions
  • All BI analysts in the Sales department have full access to data in only US regions
  • All scientists in the Sales department get access to only sales-specific data across all regions
  • Anyone outside of Sales department have no access to sales data

For this post, we consider the database salesdb, which contains the store_sales table that has store sales details. The table store_sales has the following schema.

To demonstrate the product sales analysis use case, we will consider the following personas from the Example Retail Corp:

  • Ava is a data administrator in Example Retail Corp who is responsible for supporting team members with specific data permission policies
  • Alice is a data analyst who should be able to access sales specific US store data to perform product sales analysis
  • Bob is a BI analyst who should be able to access all data from US store sales to generate reports
  • Charlie is a data scientist who should be able to access sales specific across all regions to explore and find patterns for trend analysis

Ava decides to use SageMaker Lakehouse to unify data across various data sources while setting up fine-grained access control using ABAC. Alice is excited about this decision as she can now build daily reports using her expertise with Athena. Bob now knows that he can quickly build Amazon QuickSight dashboards with queries that are optimized using Redshift’s cost-based optimizer. Charlie, being an open source Apache Spark contributor, is excited that he can build Spark based processing with Amazon EMR to build ML forecasting models.

Ava defines the user attributes as static IAM tags that could also include attributes stored in the identity provider (IdP) or as session tags dynamically to represent the user metadata. These tags are assigned to IAM users or roles and can be used to define or restrict access to specific resources or data. For more details, refer to Tags for AWS Identity and Access Management resources and Pass session tags in AWS STS.

For this post, Ava assigns users with static IAM tags to represent the user attributes, including their department membership, Region assignment, and current role relationship. The following table summarizes the tags that represent user attributes and user assignment.

User Persona Attributes Access
Alice Data Analyst Department=sales
Region=US
Role=Analyst
Sales specific data in US and no access to customer data
Bob BI Analyst Department=sales
Region=US
Role=BIAnalyst
All data in US
Charlie Data Scientist Department=sales
Region=ALL
Role=Scientist
Sales specific data in All regions and no access to customer data

Ava then defines access control policies in Lake Formation that grant or restrict access to certain resources based on predefined criteria (user attributes defined using IAM tags) being satisfied. This allows for flexible and context-aware security policies where access privileges can be adjusted dynamically by modifying the user attribute assignment without changing the policy rules. The following table summarizes the policies in the Sales department.

Access User Attributes Policy
All analysts (including Alice) in US get access to sales specific data in US regions Department=sales
Region=US
Role=Analyst
Table: store_sales (store_id, transaction_date, product_name, country, sales_price, quantity columns)
Row filter: country='US'
All BI analysts (including Bob) in US get access to all data in US regions Department=sales
Region=US
Role=BIAnalyst
Table: store_sales (all columns)
Row filter: country='US'
All scientists (including Charlie) get access to sales-specific data from all regions Department=sales
Region=ALL
Role=Scientist
Table: store_sales (all rows)
Column filter: store_id, transaction_date, product_name, country, sales_price,quantity

The following diagram illustrates the solution architecture.

Implementing this solution consists of the following high-level steps. For Example Retail, Ava as a data Administrator performs these steps:

  1. Define the user attributes and assign them to the principal.
  2. Grant permission on the resources (database and table) to the principal based on user attributes.
  3. Verify the permissions by querying the data using various analytics services.

Prerequisites

To follow the steps in this post, you must complete the following prerequisites:

  1. AWS account with access to the following AWS services:
    • Amazon S3
    • AWS Lake Formation and AWS Glue Data Catalog
    • Amazon Redshift
    • Amazon Athena
    • Amazon EMR
    • AWS Identity and Access Management (IAM)
  1. Set up an admin user for Ava. For instructions, see Create a user with administrative access.
  2. Setup S3 bucket for uploading script.
  3. Set up a data lake admin. For instructions, see Create a data lake administrator.
  4. Create IAM user named Alice and attach permissions for Athena access. For instructions, refer to Data analyst permissions.
  5. Create IAM user Bob and attach permissions for Redshift access.
  6. Create IAM user Charlie and attach permissions for EMR Serverless access.
  7. Create job runtime role: scientist_role and that will be used by Charlie. For instruction refer to: Job runtime roles for Amazon EMR Serverless
  8. Setup EMR Serverless application with Lake Formation enabled. For instruction refer to: Using EMR Serverless with AWS Lake Formation for fine-grained access control
  9. Have an existing AWS Glue database or table and Amazon Simple Storage Service (Amazon) S3 bucket that holds the table data. For this post, we use salesdb as our database, store_sales as our table, and data is stored in an S3 bucket.

Define attributes for the IAM principals Alice, Bob, Charlie

Ava completes the following steps to define the attributes for the IAM principal:

  1. Log in as an admin user and navigate to the IAM console.
  2. Choose Users under Access management in the navigation pane and search for the user Alice.
  3. Choose the user and choose the Tags tab.
  4. Choose Add new tag and provide the following key pairs:
    • Key: Department and value: sales
    • Key: Region and value: US
    • Key: Role and value: Analyst
  5. Choose Save changes.
  6. Repeat the process for the user Bob and provide the following key pairs:
    • Key: Department and value: sales
    • Key: Region and value: US
    • Key: Role and value: BIAnalyst
  7. Repeat the process for the user Charlie and IAM role scientist_role and provide the following key pairs:
    • Key: Department and value: sales
    • Key: Region and value: ALL
    • Key: Role and value: Scientist

Grant permissions to Alice, Bob, Charlie using ABAC

Ava now grants database and table permissions to users with ABAC.

Grant database permissions

Complete the following steps:

  1. Ava logs in as data lake admin and navigate to the Lake Formation console.
  2. In the navigation pane, under Permissions, choose Data lake permissions.
  3. Choose Grant.
  4. On the Grant permissions page, choose Principals by attribute.
  5. Specify the following attributes:
    • Key: Department  and value: sales
    • Key: Role and value: Analyst,Scientist
  6. Review the resulting policy expression.
  7. For Permission scope, select This account.
  8. Next, choose the catalog resources to grant access:
    • For Catalogs, enter the account ID.
    • For Databases, enter salesdb.
  9. For Database permissions, select Describe.
  10. Choose Grant.

Ava now verifies the database permission by navigating to the Databases tab under the Data Catalog and searching for salesdb. Select salesdb and choose View under Actions.

Grant table permissions to Alice

Complete the following steps to create a data filter to view sales specific columns in store_sales records whose country=US:

  1. On the Lake Formation console, choose Data filters under Data Catalog in the navigation pane.
  2. Choose Create new filter.
  3. Provide the data filter name as us_sales_salesonlydata.
  4. For Target catalog, enter the account ID.
  5. For Target database, choose salesdb.
  6. For Target table, choose store_sales.
  7. For column-level access, choose Include columns: store_id, item_code, transaction_date, product_name, country, sales_price, and quantity.
  8. For Row-level access, choose Filter rows and enter the row filter country='US'.
  9. Choose Create data filter.
  1. On the Grant permissions page, choose Principals by attribute.
  2. Specify the attributes:
    • Key: Department and value: sales
    • Key: Role as value: Analyst
    • Key: Region and value: US
  3. Review the resulting policy expression.
  4. For Permission scope, select This account.
  5. Choose the catalog resources to grant access:
    • Catalogs: Account ID
    • Databases: salesdb
    • Table: store_sales
    • Data filters: us_sales
  6. For Data filter permissions, select Select.
  7. Choose Grant.

Grant table permissions to Bob

Complete the following steps to create a data filter to view only store_sales records whose country=US:

  1. On the Lake Formation console, choose Data filters under Data Catalog in the navigation pane.
  2. Choose Create new filter.
  3. Provide the data filter name as us_sales.
  4. For Target catalog, enter the account ID.
  5. For Target database, choose salesdb.
  6. For Target table, choose store_sales.
  7. Leave Column-level access as Access to all columns.
  8. For Row-level access, enter the row filter country='US'.
  9. Choose Create data filter.

Complete the following steps to grant table permissions to Bob:

  1. On the Grant permissions page, choose Principals by attribute.
  2. Specify the attributes:
    • Key: Department and value: sales
    • Key: Role as value: BIAnalyst
    • Key: Region and value: US
  3. Review the resulting policy expression.
  4. For Permission scope, select This account.
  5. Choose the catalog resources to grant access:
    • Catalogs: Account ID
    • Databases: salesdb
    • Table: store_sales
  6. For Data filter permissions, select Select.
  7. Choose Grant.

Grant table permissions to Charlie

Complete the following steps to grant table permissions to Charlie:

  1. On the Grant permissions page, choose Principals by attribute.
  2. Specify the attributes:
    1. Key: Department and value: sales
    2. Key: Role as value: Scientist
    3. Key: Region and value: ALL
  3. Review the resulting policy expression.
  4. For Permission scope, select This account
  5. Choose the catalog resources to grant access:
    1. Catalogs: Account ID
    2. Databases: salesdb
    3. Table: store_sales
  6. For Table permissions, select Select.
  7. For Data permissions, specify the following columns: store_id, transaction_date, product_name, country, sales_price, and quantity.
  8. Choose Grant.

Alice now verifies the table permission by navigating to the Tables tab under the Data Catalog and searching for store_sales. Select store_sales and choose View under Actions. The following screenshots show the details for both sets of permissions.

Data Analyst uses Athena for building daily sales reports

Alice, the data analyst logs in to the Athena console and run the following query:

select * from "salesdb"."store_sales" limit 5

Alice has the user attributes as Department=sales, Role=Analyst, Region=US, and this attribute combination allows her access to US sales data to specific sales only column, without access to customer data as shown in the following screenshot.

BI Analyst uses Redshift for building sales dashboards

Bob, the BI Analyst, logs in to the Redshift console and run the following query:

select * from "salesdb"."store_sales" limit 10

Bob has the user attributes Department=sales, Role=BIAnalyst, Region=US, and this attribute combination allows him access to all columns including customer data for US sales data.

Data Scientist uses Amazon EMR to process sales data

Finally, Charlie logs in to the EMR console and submit the EMR job with runtime role as scientist_role. Charlie uses  the script sales_analysis.py that is uploaded to s3 bucket created for the script. He chooses the EMR Serverless application created with Lake Formation enabled.

Charlie submits batch job runs by choosing the following values:

  • Name: sales_analysis_Charlie
  • Runtime_role: scientist_role
  • Script location: <s3_script_path>/sales_analysis.py
  • For spark properties, provide key as spark.emr-serverless.lakeformation.enabled and value as true.
  • Additional configurations: Under Metastore configuration select Use AWS Glue Data Catalog as metastore. Charlie keeps rest of the configuration as default.

Once the job run is completed, Charlie can view the output by selecting stdout under Driver log files.

Charlie uses scientist_role as job runtime role with the attributes Department=sales, Role=Scientist, Region=ALL, and this attribute combination allows him access to select columns of all sales data.

Clean up

Complete the following steps to delete the resources you created to avoid unexpected costs:

  1. Delete the IAM users created.
  2. Delete the AWS Glue database and table resources created for the post, if any.
  3. Delete the Athena, Redshift and EMR resources created for the post.

Conclusion

In this post, we showcased how you can use SageMaker Lakehouse attribute-based access control, using IAM principals and session tags to simplify data access, grant creation, and maintenance. With attribute-based access control, you can manage permissions using dynamic business attributes associated with user identities and secure your data in the lakehouse by defining fine-grained permissions in the Lake Formation that are enforced across analytics and ML tools and engines.

For more information, refer to documentation. We encourage you to try out the SageMaker Lakehouse with ABAC and share your feedback with us.


About the authors

Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.

Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building data mesh solutions and sharing them with the community.

Best practices for rapidly deploying Landing Zone Accelerator on AWS

Post Syndicated from Lei Shi original https://aws.amazon.com/blogs/devops/best-practices-for-rapidly-deploying-landing-zone-accelerator-on-aws/

Landing Zone Accelerator on AWS (LZA) enables customers to deploy a flexible, configuration-driven solution to establish a landing zone while also leveraging AWS Control Tower. At AWS Professional Services, we’ve helped customers deploy and configure LZA hundreds of times. A common request we encounter is integrating LZA configuration into customers’ existing GitOps workflows. GitOps has emerged as a leading model for Infrastructure as Code (IaC), helping organizations automate and manage their cloud infrastructure. The model uses Git repositories as the single source of truth for infrastructure configuration, enabling teams to maintain consistent, version-controlled environments.

In this blog, we will focus on common LZA implementation steps based on our experience, helping customers jump-start their LZA environment and implement GitOps for their AWS infrastructure management. First, we will demonstrate how to leverage LZA while complying with your organization’s policies such as private package repositories. Next, we will guide you through a new installation of LZA that takes advantage of an auto-generated starter set of configuration files. Finally, we will direct you to another blog post that will enable you to leverage GitOps for ongoing management of your LZA configuration.

Architecture overview

The LZA solution leverages two distinct repositories; one for the LZA source code, and another for your organization’s specific configuration files. LZA creates two separate AWS CodePipelines , which are used to install the LZA solution and apply your organization’s specific configuration. Figure 1 illustrates the association between repositories and pipelines. By default, when installing LZA, the solution uses GitHub as the source and pulls the installation files published by AWS from the official LZA GitHub repository.

a diagram with icons illustrating LZA solution components

Figure 1. Landing Zone Accelerator solution components

Deploy LZA as a new install

Step 1: Preparing your enterprise private GitHub to host LZA source code.
Customers may choose to deploy LZA from the official AWS GitHub repository for LZA, but we often we find customers have policies in place that require these types of packages to be deployed from a private repository managed by the organization. For customers using GitHub privately in their enterprise, this can be as easy as cloning the LZA source code repository into your own private GitHub repository, enabling you to take advantage of policies and controls within your organization. Before moving to the next step, take a moment and clone the repository into your own private repository. A GitHub personal access token stored in AWS Secrets Manager is required to enable the stack to access your private repository. Before deploying LZA, follow these instructions to enable stack access to your repository.

Step 2: In the organization management account, install LZA as a CloudFormation Stack.

To get started, we will be going through a new installation of the LZA solution. The following steps provide specific parameter options to the CloudFormation template to support a new installation of LZA.

Specify the following parameters for Source Code Repository Configuration, see Figure 2.

  1. For Stack name, specify a name you like.
  2. For Source Location, choose github.
  3. For Repository Owner, specify your GitHub account owner ID.
  4. For Repository Name, specify your cloned LZA source code repository
  5. For Branch Name, specify the branch name of your LZA source code repository.

a screenshot of a set of parameters setting of LZA source code repo in a cloudformation stack

Figure 2. LZA installer stack parameters – source code repository

Specify the following parameters for Configuration Repository Configuration, see Figure 3.

  1. For Configuration Repository Location, choose s3.
  2. For Use Existing Config Repository, choose No.
  3. For Existing Config Repository Name, Existing Config Repository Branch Name, Existing Config Repository Owner, and Existing Config Repository CodeConnection ARN, leave blank.

We intentionally want to use S3 for the configuration repository because as the LZA solution is installed, it will auto-generate a set of starter configuration YAML files and deploy them for us in S3. This makes it very easy to get started with an initial set of customized YAML files for your environment. We choose “No” in the Use Existing Config Repository field, to have LZA to perform a new LZA installation.

a screenshot of a set of parameters setting of LZA configuration repo in a cloudformation stack

Figure 3. LZA installer stack parameters – configuration repository

  1. Choose Next, and complete the remainder of the stack settings.
  2. Finally, choose Create stack to launch the CloudFormation stack.

The installer stack typically takes minutes to complete (See Figure 4).

a screenshot showing LZA installation cloudformation stack completed successfully

Figure 4. LZA installer stack completion

Step 3: Validate two LZA pipelines are created and successfully completed in AWS CodePipeline console.

After the CloudFormation stack completes, open the AWS CodePipeline console. You’ll see a new pipeline named “AWSAccelerator-Installer” running (See Figure 5). This is the LZA Installer pipeline, and it’s connected to the GitHub source repository you specified in Step 2 above with parameters from 2 to 5. This Installer pipeline automatically generates a set of LZA configuration files stored as a compressed ZIP archive in Amazon S3. It will be designated as configuration repository of the LZA solution.

a screenshot showing LZA installer pipeline created in AWS CodePipeline successfully

Figure 5. AWSAccelerator-Installer pipeline creation

When the AWSAccelerator-Installer pipeline completes, the solution automatically creates and runs a second pipeline named “AWSAccelerator-Pipeline” as shown in Figure 6. This pipeline connects to both the GitHub source repository, and the newly created configuration repository in Amazon S3. The AWSAccelerator-Pipeline is the pipeline that manages your landing zone deployment and customization.

a screenshot showing LZA core pipeline created in AWS CodePipeline successfully

Figure 6. AWSAccelerator-Pipeline created from the AWSAccelerator-Installer pipeline

After the AWSAccelerator-Pipeline completes, your LZA solution is ready for customization.

Step 4: Migrate the LZA configuration repository from S3 to GitHub

With the AWSAccelerator-Pipeline completed, your initial landing zone is now deployed, leveraging the configuration stored in your S3 bucket. For some customers, they may need to ensure that changes to the landing zone configuration are controlled through their existing GitOps processes and tooling. See Figure 7 as an example where the S3 configuration files have been copied to a customer owned GitHub repository. This transition step can be performed in future LZA upgrade window when there is a new release of LZA source code, or right after the initial LZA installation completes in Step 3. For more information on migrating from S3 to GitHub, follow this guide to configure your AWSAccelerator-Pipelines with AWS CodeConnection.

a diagram with icons illustrating LZA solution new components with LZA configuration repo migrated to GitHub

Figure 7. CodeConnection based LZA Configuration Repository

Conclusion

In this post, we explored key steps to streamline your LZA implementation journey. By demonstrating how to work with your private package repositories, providing guidance on leveraging auto-generated configuration files, and introducing GitOps-based management, we’ve outlined a practical path to establish and maintain a robust AWS infrastructure foundation. These approaches can significantly reduce the time and complexity typically associated with LZA deployments while ensuring compliance with organizational policies. We encourage you to try these implementation steps and explore the referenced resources to enhance your AWS cloud operations. For more information about Landing Zone Accelerator, visit the AWS Landing Zone Accelerator on GitHub.

About the authors

author photo of Lei Shi

Lei Shi

Lei Shi is a Delivery Consultant at AWS Professional Services, where he transforms complex cloud challenges into elegant solutions. He focuses on enabling organizations to build secure and scalable cloud environments throughout their AWS journey.

author photo of Adam Spicer

Adam Spicer

Adam Spicer is a Principal Cloud Architect for AWS Professional Services. He works with enterprise customers to design and build their cloud infrastructure and automation to accelerate their migration to AWS. He is an avid FSU Seminole fan who loves to be on outdoor adventures with his family.

Building end-to-end data lineage for one-time and complex queries using Amazon Athena, Amazon Redshift, Amazon Neptune and dbt

Post Syndicated from Nancy Wu original https://aws.amazon.com/blogs/big-data/building-end-to-end-data-lineage-for-one-time-and-complex-queries-using-amazon-athena-amazon-redshift-amazon-neptune-and-dbt/

One-time and complex queries are two common scenarios in enterprise data analytics. One-time queries are flexible and suitable for instant analysis and exploratory research. Complex queries, on the other hand, refer to large-scale data processing and in-depth analysis based on petabyte-level data warehouses in massive data scenarios. These complex queries typically involve data sources from multiple business systems, requiring multilevel nested SQL or associations with numerous tables for highly sophisticated analytical tasks.

However, combining the data lineage of these two query types presents several challenges:

  1. Diversity of data sources
  2. Varying query complexity
  3. Inconsistent granularity in lineage tracking
  4. Different real-time requirements
  5. Difficulties in cross-system integration

Moreover, maintaining the accuracy and completeness of lineage information while providing system performance and scalability are crucial considerations. Addressing these challenges requires a carefully designed architecture and advanced technical solutions.

Amazon Athena offers serverless, flexible SQL analytics for one-time queries, enabling direct querying of Amazon Simple Storage Service (Amazon S3) data for rapid, cost-effective instant analysis. Amazon Redshift, optimized for complex queries, provides high-performance columnar storage and massively parallel processing (MPP) architecture, supporting large-scale data processing and advanced SQL capabilities. Amazon Neptune, as a graph database, is ideal for data lineage analysis, offering efficient relationship traversal and complex graph algorithms to handle large-scale, intricate data lineage relationships. The combination of these three services provides a powerful, comprehensive solution for end-to-end data lineage analysis.

In the context of comprehensive data governance, Amazon DataZone offers organization-wide data lineage visualization using Amazon Web Services (AWS) services, while dbt provides project-level lineage through model analysis and supports cross-project integration between data lakes and warehouses.

In this post, we use dbt for data modeling on both Amazon Athena and Amazon Redshift. dbt on Athena supports real-time queries, while dbt on Amazon Redshift handles complex queries, unifying the development language and significantly reducing the technical learning curve. Using a single dbt modeling language not only simplifies the development process but also automatically generates consistent data lineage information. This approach offers robust adaptability, easily accommodating changes in data structures.

By integrating Amazon Neptune graph database to store and analyze complex lineage relationships, combined with AWS Step Functions and AWS Lambda functions, we achieve a fully automated data lineage generation process. This combination promotes consistency and completeness of lineage data while enhancing the efficiency and scalability of the entire process. The result is a powerful and flexible solution for end-to-end data lineage analysis.

Architecture overview

The experiment’s context involves a customer already using Amazon Athena for one-time queries. To better accommodate massive data processing and complex query scenarios, they aim to adopt a unified data modeling language across different data platforms. This led to the implementation of both Athena on dbt and Amazon Redshift on dbt architectures.

AWS Glue crawler crawls data lake information from Amazon S3, generating a Data Catalog to support dbt on Amazon Athena data modeling. For complex query scenarios, AWS Glue performs extract, transform, and load (ETL) processing, loading data into the petabyte-scale data warehouse, Amazon Redshift. Here, data modeling uses dbt on Amazon Redshift.

Lineage data original files from both parts are loaded into an S3 bucket, providing data support for end-to-end data lineage analysis.

The following image is the architecture diagram for the solution.

Figure 1-Architecture diagram of DBT modeling based on Athena and Redshift

Some important considerations:

This experiment uses the following data dictionary:

Source table Tool Target table
imdb.name_basics DBT/Athena stg_imdb__name_basics
imdb.title_akas DBT/Athena stg_imdb__title_akas
imdb.title_basics DBT/Athena stg_imdb__title_basics
imdb.title_crew DBT/Athena stg_imdb__title_crews
imdb.title_episode DBT/Athena stg_imdb__title_episodes
imdb.title_principals DBT/Athena stg_imdb__title_principals
imdb.title_ratings DBT/Athena stg_imdb__title_ratings
stg_imdb__name_basics DBT/Redshift new_stg_imdb__name_basics
stg_imdb__title_akas DBT/Redshift new_stg_imdb__title_akas
stg_imdb__title_basics DBT/Redshift new_stg_imdb__title_basics
stg_imdb__title_crews DBT/Redshift new_stg_imdb__title_crews
stg_imdb__title_episodes DBT/Redshift new_stg_imdb__title_episodes
stg_imdb__title_principals DBT/Redshift new_stg_imdb__title_principals
stg_imdb__title_ratings DBT/Redshift new_stg_imdb__title_ratings
new_stg_imdb__name_basics DBT/Redshift int_primary_profession_flattened_from_name_basics
new_stg_imdb__name_basics DBT/Redshift int_known_for_titles_flattened_from_name_basics
new_stg_imdb__name_basics DBT/Redshift names
new_stg_imdb__title_akas DBT/Redshift titles
new_stg_imdb__title_basics DBT/Redshift int_genres_flattened_from_title_basics
new_stg_imdb__title_basics DBT/Redshift titles
new_stg_imdb__title_crews DBT/Redshift int_directors_flattened_from_title_crews
new_stg_imdb__title_crews DBT/Redshift int_writers_flattened_from_title_crews
new_stg_imdb__title_episodes DBT/Redshift titles
new_stg_imdb__title_principals DBT/Redshift titles
new_stg_imdb__title_ratings DBT/Redshift titles
int_known_for_titles_flattened_from_name_basics DBT/Redshift titles
int_primary_profession_flattened_from_name_basics DBT/Redshift
int_directors_flattened_from_title_crews DBT/Redshift names
int_genres_flattened_from_title_basics DBT/Redshift genre_titles
int_writers_flattened_from_title_crews DBT/Redshift names
genre_titles DBT/Redshift
names DBT/Redshift
titles DBT/Redshift

The lineage data generated by dbt on Athena includes partial lineage diagrams, as exemplified in the following images. The first image shows the lineage of name_basics in dbt on Athena. The second image shows the lineage of title_crew in dbt on Athena.

Figure 3-Lineage of name_basics in DBT on Athena

Figure 4-Lineage of title_crew in DBT on Athena

The lineage data generated by dbt on Amazon Redshift includes partial lineage diagrams, as illustrated in the following image.

Figure 5-Lineage of name_basics and title_crew in DBT on Redshift

Referring to the data dictionary and screenshots, it’s evident that the complete data lineage information is highly dispersed, spread across 29 lineage diagrams. Understanding the end-to-end comprehensive view requires significant time. In real-world environments, the situation is often more complex, with complete data lineage potentially distributed across hundreds of files. Consequently, integrating a complete end-to-end data lineage diagram becomes crucial and challenging.

This experiment will provide a detailed introduction to processing and merging data lineage files stored in Amazon S3, as illustrated in the following diagram.

Figure 6-Merging data lineage from Athena and Redshift into Neptune

Prerequisites

To perform the solution, you need to have the following prerequisites in place:

  • The Lambda function for preprocessing lineage files must have permissions to access Amazon S3 and Amazon Redshift.
  • The Lambda function for constructing the directed acyclic graph (DAG) must have permissions to access Amazon S3 and Amazon Neptune.

Solution walkthrough

To perform the solution, follow the steps in the next sections.

Preprocess raw lineage data for DAG generation using Lambda functions

Use Lambda to preprocess the raw lineage data generated by dbt, converting it into key-value pair JSON files that are easily understood by Neptune: athena_dbt_lineage_map.json and redshift_dbt_lineage_map.json.

  1. To create a new Lambda function in the Lambda console, enter a Function name, select the Runtime (Python in this example), configure the Architecture and Execution role, then click the “Create function” button.

Figure 7-Basic configuration of athena-data-lineage-process Lambda

  1. Open the created Lambda function and on the Configuration tab, in the navigation pane, select Environment variables and choose your configurations. Using Athena on dbt processing as an example, configure the environment variables as follows (the process for Amazon Redshift on dbt is similar):
    • INPUT_BUCKET: data-lineage-analysis-24-09-22 (replace with the S3 bucket path storing the original Athena on dbt lineage files)
    • INPUT_KEY: athena_manifest.json (the original Athena on dbt lineage file)
    • OUTPUT_BUCKET: data-lineage-analysis-24-09-22 (replace with the S3 bucket path for storing the preprocessed output of Athena on dbt lineage files)
    • OUTPUT_KEY: athena_dbt_lineage_map.json (the output file after preprocessing the original Athena on dbt lineage file)

Figure 8-Environment variable configuration for athena-data-lineage-process-Lambda

  1. On the Code tab, in the lambda_function.py file, enter the preprocessing code for the raw lineage data. Here’s a code reference using Athena on dbt processing as an example (the process for Amazon Redshift on dbt is similar). The preprocessing code for Athena on dbt’s original lineage file is as follows:

The athena_manifest.json, redshift_manifest.json, and other files used in this experiment can be obtained from the Data Lineage Graph Construction GitHub repository.

import json
import boto3
import os

def lambda_handler(event, context):
    # Set up S3 client
    s3 = boto3.client('s3')

    # Get input and output paths from environment variables
    input_bucket = os.environ['INPUT_BUCKET']
    input_key = os.environ['INPUT_KEY']
    output_bucket = os.environ['OUTPUT_BUCKET']
    output_key = os.environ['OUTPUT_KEY']

    # Define helper function
    def dbt_nodename_format(node_name):
        return node_name.split(".")[-1]

    # Read input JSON file from S3
    response = s3.get_object(Bucket=input_bucket, Key=input_key)
    file_content = response['Body'].read().decode('utf-8')
    data = json.loads(file_content)
    lineage_map = data["child_map"]
    node_dict = {}
    dbt_lineage_map = {}

    # Process data
    for item in lineage_map:
        lineage_map[item] = [dbt_nodename_format(child) for child in lineage_map[item]]
        node_dict[item] = dbt_nodename_format(item)

    # Update key names
    lineage_map = {node_dict[old]: value for old, value in lineage_map.items()}
    dbt_lineage_map["lineage_map"] = lineage_map

    # Convert result to JSON string
    result_json = json.dumps(dbt_lineage_map)

    # Write JSON string to S3
    s3.put_object(Body=result_json, Bucket=output_bucket, Key=output_key)
    print(f"Data written to s3://{output_bucket}/{output_key}")

    return {
        'statusCode': 200,
        'body': json.dumps('Athena data lineage processing completed successfully')
    }

Merge preprocessed lineage data and write to Neptune using Lambda functions

  1. Before processing data with the Lambda function, create a Lambda layer by uploading the required Gremlin plugin. For detailed steps on creating and configuring Lambda Layers, see the AWS Lambda Layers documentation.

Because connecting Lambda to Neptune for constructing a DAG requires the Gremlin plugin, it needs to be uploaded before using Lambda. The Gremlin package can be obtained from the Data Lineage Graph Construction GitHub repository.

Figure 9-Lambda layers

  1. Create a new Lambda function. Choose the function to configure. To the recently created layer, at the bottom of the page, choose Add a layer.

Figure 10_Add a layer

Create another Lambda layer for the requests library, similar to how you created the layer for the Gremlin plugin. This library will be used for HTTP client functionality in the Lambda function.

  1. Choose the recently created Lambda function to configure. Connect to Neptune through Lambda to merge the two datasets and construct a DAG. On the Code tab, the reference code to execute is as follows:
import json
import boto3
import os
import requests
from botocore.auth import SigV4Auth
from botocore.awsrequest import AWSRequest
from botocore.credentials import get_credentials
from botocore.session import Session
from concurrent.futures import ThreadPoolExecutor, as_completed

def read_s3_file(s3_client, bucket, key):
    try:
        response = s3_client.get_object(Bucket=bucket, Key=key)
        data = json.loads(response['Body'].read().decode('utf-8'))
        return data.get("lineage_map", {})
    except Exception as e:
        print(f"Error reading S3 file {bucket}/{key}: {str(e)}")
        raise

def merge_data(athena_data, redshift_data):
    return {**athena_data, **redshift_data}

def sign_request(request):
    credentials = get_credentials(Session())
    auth = SigV4Auth(credentials, 'neptune-db', os.environ['AWS_REGION'])
    auth.add_auth(request)
    return dict(request.headers)

def send_request(url, headers, data):
    try:
        response = requests.post(url, headers=headers, data=data, timeout=30)
        response.raise_for_status()
        return response.text
    except requests.exceptions.RequestException as e:
        print(f"Request Error: {str(e)}")
        if hasattr(e.response, 'text'):
            print(f"Response content: {e.response.text}")
        raise

def write_to_neptune(data):
    endpoint = 'https://your neptune endpoint name:8182/gremlin'
    # replace with your neptune endpoint name

    # Clear Neptune database
    clear_query = "g.V().drop()"
    request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': clear_query}))
    signed_headers = sign_request(request)
    response = send_request(endpoint, signed_headers, json.dumps({'gremlin': clear_query}))
    print(f"Clear database response: {response}")

    # Verify if the database is empty
    verify_query = "g.V().count()"
    request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': verify_query}))
    signed_headers = sign_request(request)
    response = send_request(endpoint, signed_headers, json.dumps({'gremlin': verify_query}))
    print(f"Vertex count after clearing: {response}")
    
    def process_node(node, children):
        # Add node
        query = f"g.V().has('lineage_node', 'node_name', '{node}').fold().coalesce(unfold(), addV('lineage_node').property('node_name', '{node}'))"
        request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
        signed_headers = sign_request(request)
        response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
        print(f"Add node response for {node}: {response}")

        for child_node in children:
            # Add child node
            query = f"g.V().has('lineage_node', 'node_name', '{child_node}').fold().coalesce(unfold(), addV('lineage_node').property('node_name', '{child_node}'))"
            request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
            signed_headers = sign_request(request)
            response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
            print(f"Add child node response for {child_node}: {response}")

            # Add edge
            query = f"g.V().has('lineage_node', 'node_name', '{node}').as('a').V().has('lineage_node', 'node_name', '{child_node}').coalesce(inE('lineage_edge').where(outV().as('a')), addE('lineage_edge').from('a').property('edge_name', ' '))"
            request = AWSRequest(method='POST', url=endpoint, data=json.dumps({'gremlin': query}))
            signed_headers = sign_request(request)
            response = send_request(endpoint, signed_headers, json.dumps({'gremlin': query}))
            print(f"Add edge response for {node} -> {child_node}: {response}")

    with ThreadPoolExecutor(max_workers=10) as executor:
        futures = [executor.submit(process_node, node, children) for node, children in data.items()]
        for future in as_completed(futures):
            try:
                future.result()
            except Exception as e:
                print(f"Error in processing node: {str(e)}")

def lambda_handler(event, context):
    # Initialize S3 client
    s3_client = boto3.client('s3')

    # S3 bucket and file paths
    bucket_name = 'data-lineage-analysis' # Replace with your S3 bucket name
    athena_key = 'athena_dbt_lineage_map.json' # Replace with your athena lineage key value output json name
    redshift_key = 'redshift_dbt_lineage_map.json' # Replace with your redshift lineage key value output json name

    try:
        # Read Athena lineage data
        athena_data = read_s3_file(s3_client, bucket_name, athena_key)
        print(f"Athena data size: {len(athena_data)}")

        # Read Redshift lineage data
        redshift_data = read_s3_file(s3_client, bucket_name, redshift_key)
        print(f"Redshift data size: {len(redshift_data)}")

        # Merge data
        combined_data = merge_data(athena_data, redshift_data)
        print(f"Combined data size: {len(combined_data)}")

        # Write to Neptune (including clearing the database)
        write_to_neptune(combined_data)

        return {
            'statusCode': 200,
            'body': json.dumps('Data successfully written to Neptune')
        }
    except Exception as e:
        print(f"Error in lambda_handler: {str(e)}")
        return {
            'statusCode': 500,
            'body': json.dumps(f'Error: {str(e)}')
        }

Create Step Functions workflow

  1. On the Step Functions console, choose State machines, and then choose Create state machine. On the Choose a template page, select Blank template.

Figure 11-Step Functions blank template

  1. In the Blank template, choose Code to define your state machine. Use the following example code:
{
  "Comment": "Daily Data Lineage Processing Workflow",
  "StartAt": "Parallel Processing",
  "States": {
    "Parallel Processing": {
      "Type": "Parallel",
      "Branches": [
        {
          "StartAt": "Process Athena Data",
          "States": {
            "Process Athena Data": {
              "Type": "Task",
              "Resource": "arn:aws:states:::lambda:invoke",
              "Parameters": {
                "FunctionName": "athena-data-lineange-process-Lambda", ##Replace with your Athena data lineage process Lambda function name
                "Payload": {
                  "input.$": "$"
                }
              },
              "End": true
            }
          }
        },
        {
          "StartAt": "Process Redshift Data",
          "States": {
            "Process Redshift Data": {
              "Type": "Task",
              "Resource": "arn:aws:states:::lambda:invoke",
              "Parameters": {
                "FunctionName": "redshift-data-lineange-process-Lambda", ##Replace with your Redshift data lineage process Lambda function name
                "Payload": {
                  "input.$": "$"
                }
              },
              "End": true
            }
          }
        }
      ],
      "Next": "Load Data to Neptune"
    },
    "Load Data to Neptune": {
      "Type": "Task",
      "Resource": "arn:aws:states:::lambda:invoke",
      "Parameters": {
        "FunctionName": "data-lineage-analysis-lambda" ##Replace with your Lambda function Name
      },
      "End": true
    }
  }
}
  1. After completing the configuration, choose the Design tab to view the workflow shown in the following diagram.

Figure 12-Step Functions design view

Create scheduling rules with Amazon EventBridge

Configure Amazon EventBridge to generate lineage data daily during off-peak business hours. To do this:

  1. Create a new rule in the EventBridge console with a descriptive name.
  2. Set the rule type to “Schedule” and configure it to run once daily (using either a fixed rate or the Cron expression “0 0 * * ? *”).
  3. Select the AWS Step Functions state machine as the target and specify the state machine you created earlier.

Query results in Neptune

  1. On the Neptune console, select Notebooks. Open an existing notebook or create a new one.

Figure 13-Neptune notebook

  1. In the notebook, create a new code cell to perform a query. The following code example shows the query statement and its results:
%%gremlin -d node_name -de edge_name
g.V().hasLabel('lineage_node').outE('lineage_edge').inV().hasLabel('lineage_node').path().by(elementMap())

You can now see the end-to-end data lineage graph information for both dbt on Athena and dbt on Amazon Redshift. The following image shows the merged DAG data lineage graph in Neptune.

Figure 14-Merged DAG data lineage graph in Neptune

You can query the generated data lineage graph for data related to a specific table, such as title_crew.

The sample query statement and its results are shown in the following code example:

%%gremlin -d node_name -de edge_name
g.V().has('lineage_node', 'node_name', 'title_crew')
  .repeat(
    union(
      __.inE('lineage_edge').outV(),
      __.outE('lineage_edge').inV()
    )
  )
  .until(
    __.has('node_name', within('names', 'genre_titles', 'titles'))
    .or()
    .loops().is(gt(10))
  )
  .path()
  .by(elementMap())

The following image shows the filtered results based on title_crew table in Neptune.

Figure 15-Filtered results based on title_crew table in Neptune

Clean up

To clean up your resources, complete the following steps:

  1. Delete EventBridge rules
# Stop new events from triggering while removing dependencies
aws events disable-rule --name <rule-name>
# Break connections between rule and targets (like Lambda functions)
aws events remove-targets --rule <rule-name> --ids <target-id>
# Remove the rule completely from EventBridge
aws events delete-rule --name <rule-name>
  1. Delete Step Functions state machine
# Stop all running executions
aws stepfunctions stop-execution --execution-arn <execution-arn>
# Delete the state machine
aws stepfunctions delete-state-machine --state-machine-arn <state-machine-arn>
  1. Delete Lambda functions
# Delete Lambda function
aws lambda delete-function --function-name <function-name>
# Delete Lambda layers (if used)
aws lambda delete-layer-version --layer-name <layer-name> --version-number <version>
  1. Clean up the Neptune database
# Delete all snapshots
aws neptune delete-db-cluster-snapshot --db-cluster-snapshot-identifier <snapshot-id>
# Delete database instance
aws neptune delete-db-instance --db-instance-identifier <instance-id> --skip-final-snapshot
# Delete database cluster
aws neptune delete-db-cluster --db-cluster-identifier <cluster-id> --skip-final-snapshot
  1. Follow the instructions at Deleting a single object to clean up the S3 buckets

Conclusion

In this post, we demonstrated how dbt enables unified data modeling across Amazon Athena and Amazon Redshift, integrating data lineage from both one-time and complex queries. By using Amazon Neptune, this solution provides comprehensive end-to-end lineage analysis. The architecture uses AWS serverless computing and managed services, including Step Functions, Lambda, and EventBridge, providing a highly flexible and scalable design.

This approach significantly lowers the learning curve through a unified data modeling method while enhancing development efficiency. The end-to-end data lineage graph visualization and analysis not only strengthen data governance capabilities but also offer deep insights for decision-making.

The solution’s flexible and scalable architecture effectively optimizes operational costs and improves business responsiveness. This comprehensive approach balances technical innovation, data governance, operational efficiency, and cost-effectiveness, thus supporting long-term business growth with the adaptability to meet evolving enterprise needs.

With OpenLineage-compatible data lineage now generally available in Amazon DataZone, we plan to explore integration possibilities to further enhance the system’s capability to handle complex data lineage analysis scenarios.

If you have any questions, please feel free to leave a comment in the comments section.


About the authors

nancynwu+photo

Nancy Wu is a Solutions Architect at AWS, responsible for cloud computing architecture consulting and design for multinational enterprise customers. Has many years of experience in big data, enterprise digital transformation research and development, consulting, and project management across telecommunications, entertainment, and financial industries.

Xu+Feng+PhotoXu Feng is a Senior Industry Solution Architect at AWS, responsible for designing, building, and promoting industry solutions for the Media & Entertainment and Advertising sectors, such as intelligent customer service and business intelligence. With 20 years of software industry experience, currently focused on researching and implementing generative AI and AI-powered data solutions.

Xu+Da+PhotoXu Da is a Amazon Web Services (AWS) Partner Solutions Architect based out of Shanghai, China. He has more than 25 years of experience in IT industry, software development and solution architecture. He is passionate about collaborative learning, knowledge sharing, and guiding community in their cloud technologies journey.

Demystify data sharing and collaboration patterns on AWS: Choosing the right tool for the job

Post Syndicated from Ramakant Joshi original https://aws.amazon.com/blogs/big-data/demystify-data-sharing-and-collaboration-patterns-on-aws-choosing-the-right-tool-for-the-job/

Data is the most significant asset of any organization. However, enterprises often encounter challenges with data silos, insufficient access controls, poor governance, and quality issues. Embracing data as a product is the key to address these challenges and foster a data-driven culture.

In this context, the adoption of data lakes and the data mesh framework emerges as a powerful approach. By decentralizing data ownership and distribution, enterprises can break down silos and enable seamless data sharing. Cataloging data, making the data searchable, implementing robust security and governance, and establishing effective data sharing processes are essential to this transformation. AWS offers services like AWS Data Exchange, AWS Glue, AWS Clean Rooms and Amazon DataZone to help organizations unlock the full potential of their data.

Personas

Let’s identify the various roles involved in the data sharing process.

First of all, there are data producers, which might include internal teams/systems, third-party producers, and partners. The data consumers include internal stakeholders/systems, external partners, and end-customers. At the core of this ecosystem lies the enterprise data platform. When considering enterprises, numerous personas come into play:

  • Line of business users – These personas need to classify data, add business context, collaborate effectively with other lines of business, gain enhanced visibility into business key performance indicators (KPIs) for improved outcomes, and explore opportunities for monetizing data
  • Partners – Partners should be able to share data, collaborate with other partners and customers.
  • Data scientists and business analysts – These personas should be able to access the data, analyze it and generate actionable business insights
  • Data engineers – Data engineers are tasked with building the proper data pipeline and cataloging the data that meets the diverse needs of stakeholders, including business analysts, data scientists, partners, and line of business users
  • Data security and governance officers – Data security involves making sure producers and consumers have appropriate access to the data, implementing right access permissions, and maintaining compliance with industry regulations, particularly in highly regulated sectors like healthcare, life sciences, and financial services. This persona is also responsible for enhancing data governance by tracking lineage, and establishing data mesh policies

Choosing the right tool for the job

Now that you have identified the various personas, it’s important to select the appropriate tools for each role:

  • Starting with the producers, if your data source includes a software as a service (SaaS) platform, AWS Glue offers options to automate data flows between software service providers and AWS services.
  • For producers seeking collaboration with partners, AWS Clean Rooms facilitates secure collaboration and analysis of collective datasets without the need to share or duplicate underlying data.
  • When dealing with third-party data sources, AWS Data Exchange simplifies the discovery, subscription, and utilization of third-party data from a diverse range of producers or providers. As a producer, you can also monetize your data through the subscription model using AWS Data Exchange.
  • Within your organization, you can democratize data with governance, using Amazon DataZone, which offers built-in governance features.
  • For SaaS consumers, AWS Glue supports bidirectional transfer and serves both as a producer and consumer tool for various SaaS providers.

Let’s briefly describe the capabilities of the AWS services we referred above:

AWS Glue is a fully managed, serverless, and scalable extract, transform, and load (ETL) service that simplifies the process of discovering, preparing, and loading data for analytics. It provides data catalog, automated crawlers, and visual job creation to streamline data integration across various data sources and targets.

AWS Data Exchange enables you to find, subscribe to, and use third-party datasets in the AWS Cloud. It also provides a platform through which a data producer can make their data available for consumption for subscribers. It is a data marketplace featuring over 300 providers offering thousands of datasets accessible through files, Amazon Redshift tables, and APIs. This service supports consolidated billing and subscription management, offering you the flexibility to explore 1,000 free datasets and samples. You don’t need to set up a separate billing mechanism or payment method specifically for AWS Data Exchange subscriptions.

AWS Clean Rooms is designed to assist companies and their partners in securely analyzing and collaborating on collective datasets without revealing or sharing underlying data. You can swiftly create a secure data clean room, fostering collaboration with other entities on the AWS Cloud to derive unique insights for initiatives such as advertising campaigns or research and development. This service protects underlying data through a comprehensive set of privacy-enhancing controls and flexible analysis rules tailored to specific business needs.

Amazon DataZone is a data management service that makes it fast and straightforward to catalog, discover, share, and govern data stored across AWS, on-premises, and third-party sources. With Amazon DataZone, administrators and data stewards who oversee an organization’s data assets can manage and govern access to data using fine-grained controls. These controls are designed to grant access with the right level of privileges and context. Amazon DataZone makes it straightforward for engineers, data scientists, product managers, analysts, and business users to access data throughout an organization so they can discover, use, and collaborate to derive data-driven insights.

Use cases

Let’s review some example use cases to understand how these diverse services can be effectively applied within a business context to achieve the desired outcomes. In this particular scenario, we focus on a company named AnyHealth, which operates in the healthcare and life sciences sector. This company encompasses multiple lines of businesses, specializing in the sale of various scientific equipment. Three key requirements have been identified:

  • Sales and customer visibility by line of business – AnyHealth wants to gain insights into the sales performance and customer demands specific to each line of business. This necessitates a comprehensive view of sales activities and customer requirements tailored to individual lines of business.
  • Cross-organization supply chain and inventory visibility – The company faces challenges related to supply chain and inventory management, especially in global crisis situations like a pandemic. They want to address instances where inventory items are idle in one line of business while there is demand for the same items in another. To overcome this, they want to establish cross-organizational visibility of supply chain and inventory data, breaking down silos and achieving prompt responses to business demands.
  • Cross-sell and up-sell opportunities – AnyHealth intends to boost sales by implementing cross-selling and up-selling strategies. To achieve this, they plan to use machine learning (ML) models to extract insights from data. These insights will then be provided to sales representatives and resellers, enabling them to identify and capitalize on opportunities effectively.

In the following sections, we discuss how to address each requirement in more detail and the AWS services that best fit each solution.

Sales and customer visibility by line of business

The first requirement involves obtaining visibility into sales and customer demand by line of business. The key consumers of this data include line of business leaders, business analysts, and various other business stakeholders.

The initial step is to ingest sales and order data into the platform. Currently, this data is centralized in the ERP system, specifically SAP. The objective is to regularly retrieve this data and capture any changes that occur. The data engineers are instrumental in building this pipeline. Given that we are dealing with a SaaS integration, AWS Glue is the logical choice for seamless data ingestion.

Next, we focus on building the enterprise data platform where the accumulated data will be hosted. This platform will incorporate robust cataloging, making sure the data is easily searchable, and will enforce the necessary security and governance measures for selective sharing among business stakeholders, data engineers, analysts, security and governance officers. In this context, Amazon DataZone is the optimal choice for managing the enterprise data platform.

As stated earlier, the first step involves data ingestion. Data is ingested from a third-party vendor SaaS solution (SAP), and the data engineer uses AWS Glue. Utilizing the SAP data connector, the data engineer establishes a connection with the SAP environment, running scheduled jobs.

The data lands in Amazon Simple Storage Service (Amazon S3). Additional AWS Glue jobs are created to transform and curate the data. The curated data is placed in a designated bucket and AWS Glue crawlers are run to catalog the data. This cataloged data is then managed through Amazon DataZone.

In Amazon DataZone, the data security officer creates the corporate domain. She/he creates producer projects and enables access to data engineers, and business analysts. Data engineers ensure sales and customer data is available from the source into the Amazon DataZone project. Business analysts enhance the data with business metadata/glossaries and publish the same as data assets or data products. The data security officer sets permissions in Amazon DataZone to allow users to access the data portal. Users can search for assets in the Amazon DataZone catalog, view the metadata assigned to them, and access the assets.

Amazon Athena is used to query, and explore the data. Amazon QuickSight is used to read from Amazon Athena and generate reports that is consumed by the line of business users and other stakeholders.

The following diagram illustrates the solution architecture using AWS services.

Cross-organization supply chain and inventory visibility

For the second requirement, the objective is to achieve visibility of supply chain and inventory across the organization. The key stakeholders remain line of business users. They would like to get a cross-organization visibility of supply chain and inventory data. The aim is to ingest supply chain and inventory information in a scheduled manner from the ERP system (SAP), and also capture any changes in the supply chain and inventory data. The persona involved in setting up the data ingestion pipeline is a data engineer. Given that we are extracting data from SAP, AWS Glue is the suitable choice for this requirement.

The next step involves obtaining economic indicators and weather information from third-party sources. AnyHealth, with its diverse lines of business, including one that manufactures medical equipment such as inhalers for asthma treatment, recognizes the significance of collecting weather information, particularly data about pollen, because it directly impacts the patient population. Additionally, socioeconomic conditions play a crucial role in government-assisted programs related to out-of-hospital care. To incorporate this third-party data, AWS Data Exchange is the logical choice.

Finally, all the accumulated data needs to be hosted on the enterprise data platform, with cataloging, and robust security and governance measures. In this context, Amazon DataZone is the preferred solution.

The pipeline begins with the ingestion of data from SAP, facilitated by AWS Glue. The data lands in Amazon S3, where AWS Glue jobs are used to curate the data, generate curated tables, and then AWS Glue crawlers are used to catalog the data.

AWS Data Exchange serves as the platform for collecting economic trends and weather information. The business analyst leverages AWS Data Exchange to retrieve data from various sources. In the AWS Data Exchange marketplace, they identify the data set, subscribe to the data, and subsequently consume it. Any changes in the source data invokes events, which updates the data object in the Amazon S3 bucket.

Amazon DataZone is used to manage and govern the datalake. Similar to the first use case, the data security officer creates a producer project. The data owner from LoB creates supply chain and inventory data assets in the producer project and publishes the same. From the consumer perspective, the data security officer also creates a consumer project, which allows the sales and marketing teams from different LoBs to search for the supply chain and inventory data published by the producer. Consumers request access to the published supply chain and inventory data, and the producer grants the necessary access. Amazon Athena is used to query, and explore the data. Amazon QuickSight is used to read from Amazon Athena and generate reports.

The following diagram illustrates this architecture.

Cross-sell and up-sell opportunities

The third requirement involves identifying cross-sell and up-sell opportunities. The key business consumers in this context are the sales representatives and resellers. AnyHealth operates globally, selling products in Europe, America, and Asia. Direct business transactions with consumers occur in America and Europe, and resellers facilitate sales in Asia, where AnyHealth lacks a direct relationship with the consumers.

The enterprise data platform is used to host and analyze the sales data and identify the customer demand. This data platform is managed by Amazon Data Zone. Cross-sell and up-sell opportunities, derived through ML models, are integrated into the customer relationship management (CRM) system, which in this case is Salesforce. Sales representatives access this data from Salesforce to engage with the market and collaborate with customers. AWS Glue is used for this integration.

Typically, resellers don’t provide their partners direct access to their customer data. Although AnyHealth doesn’t have direct access, understanding customer personas and profile information is essential to equip resellers with right offers to cross-sell and up-sell products. AWS Clean Rooms enables collaboration on collective datasets with stringent security controls, enabling insights without sharing the underlying data.

By addressing these requirements, AnyHealth can effectively identify and capitalize on cross-sell and up-sell opportunities, tailoring their approach based on the distinct dynamics of direct and reseller-based business models across various regions.

The initial step in the architecture involves a pipeline where SAP data is ingested into Amazon S3 and curated using AWS Glue job. The curated data is cataloged, governed and managed using Amazon DataZone.

In this scenario, where sales and customer information are acquired, data scientists build ML models to identify cross-sell and upsell opportunities. Using Amazon DataZone, these opportunities are shared with line of business users, providing transparency regarding the opportunities presented to sales reps and resellers. The cross-sell and upsell insights are pushed to Salesforce through AWS Glue, with an event-driven workflow for timely communication to sales reps. However, for resellers, a different pipeline is needed as AnyHealth doesn’t have direct access to the customer sales data. AnyHealth uses AWS Clean Rooms for this purpose.

With AWS Clean Rooms, the collaboration is started by AnyHealth (the collaboration initiator) who invites resellers to join. Resellers participate in the collaboration, and share the customer profile and segment information, while maintaining privacy by excluding customer names and contact details. AnyHealth uses the customer profile information and order trends to identify cross-sell and upsell opportunities. These opportunities are shared with the reseller to pursue further and position products in the market.

The following diagram illustrates this architecture.

Final architecture

Let’s now examine the complete architecture which covers all three use cases. In this architecture, purpose-built services like AWS Data Exchange, AWS Glue, AWS Clean Rooms and Amazon DataZone, have been used. The seamless integration of these services works cohesively to achieve end-to-end business objectives.

The following diagram illustrates this architecture.

To strengthen the security posture of your cloud infrastructure, we recommend using AWS Identity and Access Management (IAM), which allows you to manage access to AWS resources by creating users, groups, and roles with specific permissions. Additionally, you can use AWS Key Management Service (AWS KMS), which enables you to create, manage, and control encryption keys used to protect your data, so only authorized entities can access sensitive information. To provide an audit trail for compliance, you can use AWS CloudTrail, which records API calls made within your AWS account.

Conclusion

In this post, we discussed how to choose right tool for building an enterprise data platform and enabling data sharing, collaboration and access within your organization and with third-party providers. We addressed three business use cases using AWS Glue, AWS Data Exchange, AWS Clean Rooms, and Amazon DataZone through three different use cases.

To learn more about these services, check out the AWS Blogs for Amazon DataZone, AWS Glue, AWS Clean Rooms, and AWS Data Exchange.


About the authors

Ramakant Joshi is an AWS Solutions Architect, specializing in the analytics and serverless domain. He has a background in software development and hybrid architectures, and is passionate about helping customers modernize their cloud architecture.

Debaprasun Chakraborty is an AWS Solutions Architect, specializing in the analytics domain. He has around 20 years of software development and architecture experience. He is passionate about helping customers in cloud adoption, migration and strategy.

Using Amazon GuardDuty Malware Protection to scan uploads to Amazon S3

Post Syndicated from Luke Notley original https://aws.amazon.com/blogs/security/using-amazon-guardduty-malware-protection-to-scan-uploads-to-amazon-s3/

Amazon Simple Storage Service (Amazon S3) is a widely used object storage service known for its scalability, availability, durability, security, and performance. When sharing data between organizations, customers need to treat incoming data as untrusted and assess it for malicious files before ingesting it into their downstream processes. This traditionally requires setting up secure staging buckets, deploying third-party anti-virus and anti-malware scanning software, and managing a complex data pipeline and processing architecture.

To address the need for malware protection in Amazon S3, Amazon Web Services (AWS) has launched Amazon GuardDuty Malware Protection for Amazon S3. This new feature provides malicious object scanning for objects uploaded to S3 buckets, using multiple AWS-developed and industry-leading third-party malware scanning engines. It eliminates the need for customers to manage their own isolated data pipelines, compute infrastructure, and anti-virus software across accounts and AWS Regions, providing malware detection without compromising the scale, latency, and resiliency of S3 usage.

In this blog post, we share a solution that uses Amazon EventBridge, AWS Lambda, and Amazon S3 to copy scanned S3 objects to a destination S3 bucket. EventBridge is a serverless event bus that you can use to build event-driven architectures and automate your business workflows. In this solution, we allow events to be invoked from an object that is being placed in an S3 bucket. The events can be processed by a serverless function in Lambda to invoke a malware scan. We then show you how to extend this solution for other use cases specific to your organization.

Feature overview

GuardDuty Malware Protection for Amazon S3 provides a malware and anti-virus detection service for new objects uploaded to an S3 bucket. Malware Protection for S3 is enabled from within the AWS Management Console for GuardDuty and GuardDuty threat detection is not required to be enabled to use this feature. If GuardDuty threat detection is enabled, security findings for detected malware are also sent to GuardDuty. This allows customer development or application teams and security teams to work together and oversee malware protection for S3 buckets throughout the organization.

When your AWS account has GuardDuty enabled in an AWS Region, your account is associated to a unique regional entity called a detector ID. All findings that GuardDuty generates and API operations that are performed are associated with this detector ID. If you don’t want to use GuardDuty with your AWS account, Malware Protection for S3 is available as an independent feature. Used independently, Malware Protection for S3 will not create an associated detector ID.

When a malware scan identifies a potentially malicious object and you don’t have a detector ID, no GuardDuty finding will be generated in your AWS account. GuardDuty will publish the malware scan results to your default EventBridge event bus and metrics to an Amazon CloudWatch namespace for you to use for automating additional tasks.

GuardDuty manages error handling and reprocessing of event creation and publication as needed to make sure that each object is properly evaluated before being accessed by downstream resources. GuardDuty supports configuring Amazon S3 object tagging actions to be performed throughout the process.

Figure 1 shows the high-level overview of the S3 object scanning process.

Figure 1: S3 object scanning process

Figure 1: S3 object scanning process

The object scanning process is the following:

  1. An object is uploaded to an S3 bucket that has been configured for malware detection. If the object is uploaded as a multi-part upload, then a new object notification will be generated on completion of the upload.
  2. The malware scan service receives a notification that a new object has been detected in the bucket.
  3. The malware scan service downloads the object by using AWS PrivateLink. This will be automatically created when malware detection is enabled on an S3 bucket. No additional configuration is required.
  4. The malware detection service then reads, decrypts, and scans this object in an isolated VPC with no internet access within the GuardDuty service account. Encryption at rest is used for customer data that is scanned during this process. After the malware detection scan is complete, the object is deleted from the malware scanning environment.
  5. The malware scan result event is sent to the EventBridge default event bus in your AWS account and Region where malware detection has been enabled. When malware is detected, an EventBridge notification is generated that includes details of which S3 object was flagged as malicious and supporting information such as the malware variant and known use cases for the malicious software.
  6. Scan metrics such as number of objects scanned and bytes scanned are sent to Amazon CloudWatch.
  7. If malware is detected, the service sends a finding to the GuardDuty detector ID in the current Region.
  8. If you have configured object tagging, GuardDuty adds a predefined tag with key GuardDutyMalwareScanStatus and a potential scan result value of your scanned S3 object.

IAM permissions

Enabling and using GuardDuty Malware Protection for S3 requires you to add AWS Identity and Access Manager (IAM) role permissions and a specific trust policy for GuardDuty to perform the malware scan on your behalf. GuardDuty provides you flexibility to enable this feature for your entire bucket, or limit the scope of the malware scan to specific object prefixes where GuardDuty scans each uploaded object that starts with up to five selected prefixes.

To allow GuardDuty Malware Protection for S3 to scan and add tags to your S3 objects, you need an IAM role that includes permissions to perform the following tasks:

  1. A trust policy to allow Malware Protection to assume the IAM role.
  2. Allow EventBridge actions to create and manage the EventBridge managed rule to allow Malware Protection for S3 to listen to your S3 object notifications.
  3. Allow Amazon S3 and EventBridge actions to send notification to EventBridge for events in the S3 bucket.
  4. Allow Amazon S3 actions to access the uploaded S3 object and add a predefined tag GuardDutyMalwareScanStatus to the scanned S3 object.
  5. If you’re encrypting S3 buckets with AWS Key Management System (AWS KMS) keys, you must allow AWS KMS key actions to access the object before scanning and putting a test object in S3 buckets with the supported encryption.

This IAM policy is required each time you enable Malware Protection for S3 for a new bucket in your account. Alternatively, update an existing IAM PassRole policy to include the details of another S3 bucket resource each time you enable Malware Protection. See the AWS documentation for example policies and permissions required.

S3 object tagging and access control

When you enable S3 object tagging, GuardDuty adds a predefined tag with key GuardDutyMalwareScanStatus and a potential scan result value of your scanned S3 object. These tags enable the implementation of a tag-based access control (TBAC) policy for the objects, halting access to an S3 object until a malware scan has been completed.

The example S3 bucket policy in the AWS GuardDuty user guide stops anyone other than the GuardDuty Malware scan service principal from reading objects from the specific S3 bucket that aren’t tagged GuardDutyMalwareScanStatus with a value NO_THREATS_FOUND. The policy also helps prevent other roles or users other than GuardDuty from adding the GuardDutyMalwareScanStatus tag.

Configure optional access for other IAM roles that are allowed to override the GuardDutyMalwareScanStatus tag after an object is tagged. Achieve this by replacing <IAM-role-name> in the following example S3 bucket policy.

{
            "Sid": "OnlyGuardDutyCanTag",
            "Effect": "Deny",
            "NotPrincipal": {
                "AWS": [
                    "arn:aws:iam::555555555555:root",
                    "arn:aws:iam::555555555555:role/<IAM-role-name>",
                    "arn:aws:iam::555555555555:assumed-role/<IAM-role-name>/GuardDutyMalwareProtection"
                ]
            },

Change the policy if you are required to allow certain principals or roles to read failed or skipped objects. You can permit a special role to read the malicious object if needed as part of your existing incident response process. Do this by adding an additional statement into the S3 bucket policy and replacing the <IAM-role-name>value in the following example.

{
            "Sid": "AllowSecurityTeamReadMalicious",
            "Effect": "Deny",
            "NotPrincipal": {
                "AWS": [
                    "arn:aws:iam::555555555555:role/<IAM-role-name>"
                ]
            },
            "Action": [
                "s3:GetObject",
                "s3:GetObjectVersion"
            ],
            "Resource": [
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET",
                "arn:aws:s3:::DOC-EXAMPLE-BUCKET/*"
            ],
            "Condition": {
                "StringNotEquals": {
                    "s3:ExistingObjectTag/GuardDutyMalwareScanStatus": "THREATS_FOUND"
                }
            }
        },

Solution overview

This solution is designed to streamline the deployment of GuardDuty Malware Protection for S3, helping you to maintain a secure and reliable S3 storage environment while minimizing the risk of malware infections and their potential consequences. The solution provides several configuration options, allowing you to create a new S3 bucket or use an existing one, enable encryption with a new or existing AWS KMS key, and optionally set up a function to copy objects with a defined tag to a destination S3 bucket. The copy function feature offers an additional layer of protection by separating potentially malicious files from clean ones, allowing you to maintain a separate repository of safe data for continued business operations or further analysis.

Figure 2 shows the solution architecture.

Figure 2: Amazon GuardDuty copy S3 object solution overview

Figure 2: Amazon GuardDuty copy S3 object solution overview

The high-level workflow of the solution is as follows:

  1. An object is uploaded to an S3 bucket that has been configured for malware detection.
  2. The malware scan service receives a notification that a new object has been detected in the bucket and then GuardDuty reads, decrypts, and scans the object in an isolated environment.
  3. An EventBridge rule is configured to listen for events that match the pattern of completed scans for the monitored bucket that have a scan result of NO_THREATS_FOUND.
  4. When the matched event pattern occurs, the copy object Lambda function is invoked.
  5. The Lambda copy object function copies the object from the monitored S3 bucket to the target bucket.

In this solution, you will use the follow AWS services and features:

  • Event tracking: This solution uses an EventBridge rule to listen for completed malware scan result events for a specific S3 bucket, which has been enabled for malware scanning. When the EventBridge rule finds a matched event, the rule passes the required parameters and invokes the Lambda function required to copy the S3 object from the source malware protected bucket to a destination clean bucket. The event pattern used in this solution uses the following format:
    {
      "source": ["aws.guardduty"],
      "detail-type": ["GuardDuty Malware Protection Object Scan Result"],
      "detail": {
        "scanStatus": ["COMPLETED"],
        "resourceType": ["S3_OBJECT"],
        "s3ObjectDetails": {
          "bucketName": ["<DOC-EXAMPLE-BUCKET-111122223333>"]
        },
        "scanResultDetails": {
          "scanResultStatus": ["NO_THREATS_FOUND"]
        }
      }
    }

    Note: Replace the value of the bucketName attribute with the bucket in your account.

  • Task orchestration: A Lambda function handles the logic for copying the S3 object from the source bucket to the destination bucket which has just been scanned by GuardDuty. If the object was created within a new S3 prefix, the prefix and the object will be copied. If the object was tagged by GuardDuty, then the object tag will be copied.

Deploy the solution

The solution CloudFormation template provides you with multiple deployment scenarios so you can choose which best applies to your use case.

Deploy the CloudFormation template

For this next step, make sure that you deploy the CloudFormation template provided in the AWS account and Region where you want to test this solution.

To deploy the CloudFormation template

  1. Choose the Launch Stack button to launch a CloudFormation stack in your account. Note that the stack will launch in the N. Virginia (us-east-1) Region. To deploy this solution in other Regions, download the solution’s CloudFormation template, modify it, and deploy it to the selected Regions.

    Launch Stack

  2. Choose the appropriate scenario and complete the parameters information questions as shown in Figure 3.

    Figure 3: CloudFormation template parameters

    Figure 3: CloudFormation template parameters

    Each of the following scenarios and their parameter information (from Figure 3) can be evaluated to make sure that the CloudFormation template deploys successfully:

    Deployment scenario

    • Create a new bucket or use an existing bucket?
    • If ”new”, should a KMS key be created for the new bucket?
    • Would you like to create the copy function to a destination bucket? Create the Lambda copy function from the protected bucket to the clean bucket.

    Post scan file copy function

    • This will be used as the basis for the copy function and EventBridge rule to invoke the function: Copy files to the clean bucket with either the THREATS or NO_THREATS_FOUND tagged value.

    Existing S3 bucket configuration – not used for new S3 buckets

    • Enter the bucket name that you would like to be your scanned bucket: Enter the existing S3 bucket name that will be enabled for GuardDuty Malware Protection for S3.
    • Enter the bucket name that you would like to be your scanned bucket: Enter the S3 bucket name to be used as the copy destination for S3 objects.
    • Is the existing bucket using a KMS key? Is the existing S3 bucket encrypted with an existing KMS key?
    • ARN of the existing KMS key to be used: Provide the existing KMS key Amazon Resource Name (ARN) to be used for KMS encryption. IAM policies will be configured for this KMS key name.
    • Lambda Copy Function clean bucket: Create a new S3 bucket with the Lambda copy function from the protected bucket to the clean bucket.
  3. Review the stack name and the parameters for the template.
  4. On the Quick create stack screen, scroll to the bottom and select I acknowledge that AWS CloudFormation will create IAM resources.
  5. Choose Create stack. The deployment of the CloudFormation stack will take 3–4 minutes.

After the CloudFormation stack has deployed successfully, the solution will be available for use in the same Region where you deployed the CloudFormation stack. The solution deploys a specific Lambda function and EventBridge rule to match the name of the source S3 bucket.

Deploy the AWS CDK template

Alternatively if you prefer to use AWS CDK, download the CDK code from the GitHub repository.

Follow the readme contained within the repository to deploy the solution or individual components depending your requirements.

Extend the solution

In this section, you’ll find options for extending the solution.

Copy alternative status results

The solution can be extended to copy S3 objects with a scan result status that you define. To change the scan result used to invoke the copy function, update the scanresultstatus in the event pattern defined in EventBridge rule created as part of the solution named S3Malware-CopyS3Object-<DOC-EXAMPLE-BUCKET-111122223333>.

"scanResultDetails": {
      "scanResultStatus": ["<scan result status>"]

Delete source S3 objects

To delete the object from the source after the copy was successful, you will need to update the Lambda function code and the IAM role used by the Lambda function.

The IAM role used by the Lambda function requires a new statement added to the existing role. The JSON formatted statement is provided in the following example.

{
			"Action": [
				"s3:DeleteObject"
					],
			"Resource": [
				"arn:aws:s3:::<DOC-EXAMPLE-BUCKET-111122223333>/*"
			],
			"Effect": "Allow",
			"Sid": "AllowDeleteObjectSourceBucket"
		},

The copy Lambda function requires the following lines to be added at the end of the function code to delete the object:

s3.delete_object(Bucket=SOURCE_BUCKET,Key=SOURCE_KEY)

Scan existing S3 objects

When GuardDuty Malware Protection for S3 is enabled, it scans only new objects put into the bucket. To scan existing objects in a S3 bucket for malware, set up bucket replication to replicate all objects from a source bucket to a destination bucket with Malware Protection enabled.

Automate tagged object deletion

To remove malicious objects from the S3 bucket to help prevent accidental download or access, implement a tag-based lifecycle rule to delete the object after a specific number of days. To achieve this follow the steps in Setting a lifecycle configuration on a bucket to configure a lifecycle rule and make sure the tag key is GuardDutyMalwareScanStatus and value is THREATS_FOUND.

Figure 4: Tag based S3 lifecycle rule

Figure 4: Tag based S3 lifecycle rule

Align the lifecycle policy with your organization’s current S3 object malware investigation procedures. Deleting objects prematurely might hinder security teams’ ability to analyze potentially malicious content. When using bucket versioning instead of permanently deleting the object, Amazon S3 inserts a delete marker that becomes the current version of the object.

AWS Transfer Family integration

If you’re using the AWS Transfer Family service with Secure File Transfer Protocol (SFTP) connector for S3, it’s recommended to scan external uploads for malware before using the received files. This helps ensure the security and integrity of data transferred into your S3 buckets using SFTP.

Figure 5: AWS Transfer Family S3 workflow

Figure 5: AWS Transfer Family S3 workflow

To implement malware scanning, configure a file processing workflow configuration to copy the uploaded objects into an S3 bucket that has GuardDuty Malware Protection for S3 enabled.

Figure 6: Transfer Family configuration workflow

Figure 6: Transfer Family configuration workflow

Summary

Amazon GuardDuty Malware Protection for S3 is now available to assess untrusted objects for malicious files before being ingested by downstream processes within your organization. Customers can automatically scan their S3 objects for malware and take appropriate actions, such as quarantining or remediating infected files. This proactive approach helps mitigate the risks associated with malware infections, data breaches, and potential financial losses. The solution provided offers an additional layer of protection by separating potentially malicious files from clean ones, allowing customers to maintain a separate repository of safe data for continued business operations or further analysis. Visit the 2024 re:Inforce session or the what’s new blog post to understand additional service details.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
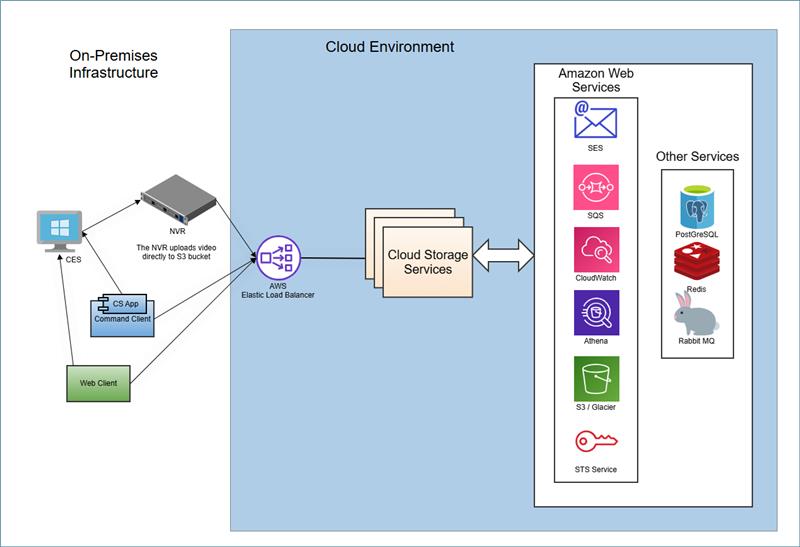
Luke Notley

Luke Notley
Luke is a Senior Solutions Architect with Amazon Web Services and is based in Western Australia. Luke has a passion for helping customers connect business outcomes with technology and assisting customers throughout their cloud journey, helping them design scalable, flexible, and resilient architectures. In his spare time, he enjoys traveling, coaching basketball teams, and DJing.

Arran Peterson

Arran Peterson
Arran, a Solutions Architect based in Adelaide, South Australia, collaborates closely with customers to deeply understand their distinct business needs and goals. His role extends to assisting customers in recognizing both the opportunities and risks linked to their decisions related to cloud solutions.

Migrate data from an on-premises Hadoop environment to Amazon S3 using S3DistCp with AWS Direct Connect

Post Syndicated from Vicky Jacob original https://aws.amazon.com/blogs/big-data/migrate-data-from-an-on-premises-hadoop-environment-to-amazon-s3-using-s3distcp-with-aws-direct-connect/

This post demonstrates how to migrate nearly any amount of data from an on-premises Apache Hadoop environment to Amazon Simple Storage Service (Amazon S3) by using S3DistCp on Amazon EMR with AWS Direct Connect.

To transfer resources from a target EMR cluster, the traditional Hadoop DistCp must be run on the source cluster to move data from one cluster to another, which invokes a MapReduce job on the source cluster and can consume a lot of cluster resources (depending on the data volume). To avoid this problem and minimize the load on the source cluster, you can use S3DistCp with Direct Connect to migrate terabytes of data from an on-premises Hadoop environment to Amazon S3. This process runs the job on the target EMR cluster, minimizing the burden on the source cluster.

This post provides instructions for using S3DistCp for migrating data to the AWS Cloud. Apache DistCp is an open source tool that you can use to copy large amounts of data. S3DistCp is similar to DistCp, but optimized to work with AWS, particularly Amazon S3. When compared to Hadoop DistCp, S3DistCp is more scalable, with higher throughput and efficient for parallel copying of large numbers of objects across s3 buckets and across AWS accounts.

Solution overview

The architecture for this solution includes the following components:

  • Source technology stack:
    • A Hadoop cluster with connectivity to the target EMR cluster over Direct Connect
  • Target technology stack:

The following architecture diagram shows how you can use the S3DistCp from the target EMR cluster to migrate huge volumes of data from an on-premises Hadoop environment through a private network connection, such as Direct Connect to Amazon S3.

S3DistCpThis migration approach uses the following tools to perform the migration:

  • S3DistCp – S3DistCp is similar to DistCp, but optimized to work with AWS, particularly Amazon S3. The command for S3DistCp in Amazon EMR version 4.0 and later is s3-dist-cp, which you add as a step in a cluster or at the command line. With S3DistCp, you can efficiently copy large amounts of data from Amazon S3 into Hadoop Distributed Filed System (HDFS), where it can be processed by subsequent steps in your EMR cluster. You can also use S3DistCp to copy data between S3 buckets or from HDFS to Amazon S3. S3DistCp is more scalable and efficient for parallel copying of large numbers of objects across buckets and across AWS accounts.
  • Amazon S3 – Amazon S3 is an object storage service. You can use Amazon S3 to store and retrieve any amount of data at any time, from anywhere on the web.
  • Amazon VPC – Amazon VPC provisions a logically isolated section of the AWS Cloud where you can launch AWS resources in a virtual network that you’ve defined. This virtual network closely resembles a traditional network that you would operate in your own data center, with the benefits of using the scalable infrastructure of AWS.
  • AWS Identity and Access Management (IAM) – IAM is a web service for securely controlling access to AWS services. With IAM, you can centrally manage users, security credentials such as access keys, and permissions that control which AWS resources users and applications can access.
  • Direct Connect – Direct Connect links your internal network to a Direct Connect location over a standard ethernet fiber-optic cable. One end of the cable is connected to your router, the other to a Direct Connect router. With this connection, you can create virtual interfaces directly to public AWS services (for example, to Amazon S3) or to Amazon VPC, bypassing internet service providers in your network path. A Direct Connect location provides access to AWS in the AWS Region with which it’s associated. You can use a single connection in a public Region or in AWS GovCloud (US) to access public AWS services in all other public Regions.

In the following sections, we discuss the steps to perform the data migration using S3DistCp.

Prerequisites

Before you begin, you should have the following prerequisites:

Get the active NameNode from the source Hadoop cluster

Sign in to any of the nodes on the source cluster and run the following commands on bash to get the active NameNode on the cluster.

In newer versions of Hadoop, run the following command to get the service status, which will list the active NameNode on the cluster:

[hadoop@hadoopcluster01 ~]$ hdfs haadmin -getAllServiceState
hadoopcluster01.test.amazon.local:8020                active
hadoopcluster02.test.amazon.local:8020                standby
hadoopcluster03.test.amazon.local:8020                standby

On older versions of Hadoop, run the following method on bash to get the active NameNode on the cluster:

[hadoop@hadoopcluster01 ~]$ getActiveNameNode(){
    nameservice=$(hdfs getconf -confKey dfs.nameservices);
    ns=$(hdfs getconf -confKey dfs.ha.namenodes.${nameservice});
    IFS=',' read -ra ADDR <<< "$ns"
    activeNode=''
    for n in "${ADDR[@]}"; do
        state=$(hdfs haadmin -getServiceState $n)
        if [ $state = "active" ]; then
            echo "$state ==>$n"
            activeNode=$n
        fi
    done
    activeNodeFQDN=$(hdfs getconf -confKey dfs.namenode.rpc-address.${nameservice}.${activeNode})
    echo $activeNodeFQDN;
}

[hadoop@hadoopcluster01 ~]$ getActiveNameNode
active ==>namenode863
hadoopcluster01.test.amazon.local:8020

Validate connectivity from the EMR cluster to the source Hadoop cluster

As mentioned in the prerequisites, you should have an EMR cluster and attach a custom IAM role for Amazon EMR. Run the following command to validate the connectivity from the target EMR cluster to the source Hadoop cluster:

[hadoop@emrcluster01 ~]$ telnet hadoopcluster01.test.amazon.local 8020
Trying 192.168.0.1...
Connected to hadoopcluster01.test.amazon.local.
Escape character is '^]'.
^]

Alternatively, you can run the following command:

[hadoop@emrcluster01 ~]$ curl -v telnet://hadoopcluster01.test.amazon.local:8020
*   Trying 192.168.0.1:8020...
* Connected to hadoopcluster01.test.amazon.local (192.168.0.1) port 8020 (#0)

Validate if the source HDFS path exists

Check if the source HDFS path is valid. If the following command returns 0, indicating that it’s valid, you can proceed to the next step:

[hadoop@emrcluster01 ~]$ hdfs dfs -test -d hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01
[hadoop@emrcluster01 ~]$ echo $?
0

Transfer data using S3DistCp

To transfer the source HDFS folder to the target S3 bucket, use the following command:

s3-dist-cp --src hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 --dest s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01

To transfer large files in multipart chunks, use the following command to set the chuck size:

s3-dist-cp --src hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 --dest s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01 --multipartUploadChunkSize=1024

This will invoke a MapReduce job on the target EMR cluster. Depending on the volume of the data and the bandwidth speed, the job can take a few minutes up to a few hours to complete.

To get the list of running yarn applications on the cluster, run the following command:

yarn application -list

Validate the migrated data

After the preceding MapReduce job completes successfully, use the following steps to validate the data copied over:

source_size=$(hdfs dfs -du -s hdfs://hadoopcluster01.test.amazon.local/user/hive/warehouse/test.db/test_table01 | awk -F' ' '{print $1}')
target_size=$(aws s3 ls --summarize --recursive s3://<BUCKET_NAME>/user/hive/warehouse/test.db/test_table01 | grep "Total Size:" | awk -F' ' '{print $3}')

printf "Source HDFS folder Size in bytes: $source_size"
printf "Target S3 folder Size in bytes: $target_size" 

If the source and target size aren’t equal, perform the cleanup step in the next section and repeat the preceding S3DistCp step.

Clean up partially copied or errored out partitions and files

S3DistCp doesn’t clean up partially copied files and partitions if it fails while copying. Clean up partially copied or errored out partitions and files before you reinitiate the S3DistCp process. To clean up objects on Amazon S3, use the following AWS CLI command to perform the delete operation:

aws s3 rm s3://<BUCKET_NAME>/path/to/the/object –recursive

Best practices

To avoid copy errors when using S3DistCP to copy a single file (instead of a directory) from Amazon S3 to HDFS, use Amazon EMR 5.33.0 or later, or Amazon EMR 6.3.0 or later.

Limitations

The following are limitations of this approach:

  • If S3DistCp is unable to copy some or all of the specified files, the cluster step fails and returns a non-zero error code. If this occurs, S3DistCp doesn’t clean up partially copied files.
  • S3DistCp doesn’t support concatenation for Parquet files. Use PySpark instead. For more information, see Concatenating Parquet files in Amazon EMR.
  • VPC limitations apply to Direct Connect for Amazon S3. For more information, see AWS Direct Connect quotas.

Conclusion

In this post, we demonstrated the power of S3DistCp to migrate huge volumes of data from a source Hadoop cluster to a target S3 bucket or HDFS on an EMR cluster. With S3DistCp, you can migrate terabytes of data without affecting the compute resources on the source cluster as compared to Hadoop DistCp.

For more information about using S3DistCp, see the following resources:


About the Author

Vicky Wilson Jacob is a Senior Data Architect with AWS Professional Services Analytics Practice. Vicky specializes in Big Data, Data Engineering, Machine Learning, Data Science and Generative AI. He is passionate about technology and solving customer challenges. At AWS, he works with companies helping customers implement big data, machine learning, analytics, and generative AI solutions on cloud. Outside of work, he enjoys spending time with family, singing, and playing guitar.

Secure file sharing solutions in AWS: A security and cost analysis guide, Part 1

Post Syndicated from Sumit Bhati original https://aws.amazon.com/blogs/security/how-to-securely-transfer-files-with-presigned-urls/

July 28, 2025: This post has been updated and expanded into a comprehensive two-part series covering multiple AWS file sharing solutions. This new series provides in-depth analysis of security and cost considerations to help you make informed decisions based on your requirements.


Note: This is Part 1 of a two-part post. You can read Part 2 here.

Sharing files with an outside entity—to share data between business partners or facilitate customer access to files—is a common use case for Amazon Web Services (AWS) customers. Organizations must balance security, cost, and usability. In a business-to-business data sharing scenario, these challenges become even more complex because human interaction is often minimal or absent, requiring robust automated solutions. Many AWS services offer multiple options for granting access. The one that’s best for your use case depends on multiple factors.

This post helps you decide which AWS services to use to implement a file sharing approach that suits your business needs. We focus on security controls and cost implications, describe some of the trade-offs, and highlight key differences to help you make an informed decision based on your specific requirements. We go through each option, highlighting their strengths and limitations, and provide guidance on choosing the right solution for your use case.

Understand your needs first

The first step in designing an AWS file sharing solution is to develop a clear understanding of your requirements and constraints. Because there are several possible design patterns and a number of different AWS services to consider, you need to start by identifying and prioritizing the features that you need. Gather the following information to guide your approach:

Access patterns and scale

When planning for access patterns and scale, there are a few key factors to keep in mind. First, consider how files are shared—machine-to-machine, human-to-machine, or human-to-human—because that impacts security and performance. Then, think about transfer frequency—are files exchanged only once a day, or are thousands moving every hour? If download control matters, setting limits on how often a file can be accessed might be necessary. File sizes also play a role, from typical everyday transfers to the largest files you need to support. Finally, total data volume shapes how much information you’ll be transferring on a regular basis.

Technical requirements

Your choice of solution will be influenced by technical constraints and capabilities. Protocol requirements often drive initial decisions, such as whether you need SFTP, FTPS, or HTTPS access. Consider existing systems that must interface with your solution and how they’ll connect. Performance considerations span several dimensions: acceptable latency for file transfers, geographic distribution of your users, bandwidth requirements, and whether you need built-in retry mechanisms for failed transfers. Additionally, think about how many simultaneous transfers your solution needs to support.

Security and compliance

Security and compliance requirements will definitely influence your file sharing strategy. Consider who controls encryption keys—whether managed by AWS or your organization—and what key rotation policies are needed. Authentication needs often vary—you might be authenticating individual users, specific systems, or entire business entities, using methods ranging from passwords to API keys, multi-factor authentication, or certificates. Your audit requirements will influence your choices in logging and monitoring capabilities. You might have geographic considerations like data sovereignty requirements, storage location restrictions, and access controls that consider the recipient’s location. If your data is subject to a law, like GDPR in Europe or HIPAA in the United States, or if your data is regulated by a standard like the Payment Card Industry’s Data Security Standard (PCI-DSS), you will need to consult with your own legal and compliance advisors to see what is required. When assessing risk tolerance, consider the security triad of confidentiality, integrity, and availability—some use cases might tolerate brief periods of unavailability but cannot risk data exposure, while others prioritize continuous availability.

Operational requirements

Day-to-day operations bring their own set of considerations. File retention policies determine how long data needs to be kept, while auto-deletion capabilities might be necessary for managing storage and compliance. Consider what kind of reporting and monitoring of file transfer activities you need. Do you need monthly reports, daily reports or perhaps detailed real-time tracking of transfer activities. By adding handling and notification systems, you can help make sure that problems are caught and addressed promptly. Disaster recovery requirements, expressed through recovery point objectives (RPO) and recovery time objectives (RTO), help determine the resilience needed in your solution.

Business constraints

Your solution must operate within your business constraints, such as budget limitations, technical limitations, timelines, available expertise, and service level agreements (SLAs). Budget limitations include initial implementation costs and ongoing operational expenses. Consider other parties’ technical limitations—they might use specific protocols such as SFTP, require mobile device compatibility, or operate older systems that have limited cryptographic capabilities. Implementation timelines influence choices between managed services that can be deployed quickly and custom solutions that require more time and expertise. The expertise available for solution maintenance is also a consideration. SLAs for file transfers might specify availability and performance requirements that you’re obligated to meet. To meet these constraints, you must estimate how much your file sharing needs will grow over time and determine if you need a regional or a global solution.

By carefully considering these aspects, you’ll be better prepared to evaluate different AWS file sharing solutions and select the one that best fits your use case. Understanding your requirements for uploads and downloads will help determine if your use case can be supported through a single AWS service or needs a combination of services.

Solutions

Let’s start by looking at the various file sharing mechanisms that AWS supports. The following table identifies the key AWS services needed for each solution, describes the security and cost implications of the solutions, and describes their complexity and protocol support capabilities. The following table shows the solutions described in this post.

Solution AWS services Security features Cost* Region control
AWS Transfer Family Transfer Family, Amazon S3, API Gateway, and Lambda Managed security, encryption in transit and at rest, IAM integration, and custom authentication $0.30 per hour per protocol, data transfer fees, and storage costs Can deploy to specific AWS Regions, can only transfer files to and from S3 buckets in the same Region
Transfer Family web apps Transfer Family, S3, and CloudFront Browser-based access, IAM Identity Center integration, and S3 Access Grants Pay-per-file operation, CloudFront costs, and storage costs Uses CloudFront (global) for web access, but backend components can be Region-specific
Amazon S3 pre-signed URLs S3 Time-limited URLs, IAM controls for URL generation, and HTTPS S3 request and data transfer fees Can be restricted to specific Regions
Serverless application with Amazon S3 presigned URLs S3, AWS Lambda, and API Gateway Time-limited URLs, HTTPS, IAM controls, customizable authentication Pay per request and minimal infrastructure cost Components can be Region-specific

The following table shows the solutions described in Part 2.

Solution AWS services Security features Cost* Region control
CloudFront signed URLs CloudFront, Amazon S3, and Lambda Optional edge security using AWS Lambda@Edge, AWS WAF integration, SSL/TLS, geo restrictions, and AWS Shield Standard (included automatically) Content delivery network (CDN) costs, request pricing, and data transfer fees Global service by design; origin can be AWS Region-specific
Amazon VPC endpoint service PrivateLink, VPC, and NLB Complete network isolation, private connectivity, and multi-layer security Endpoint hourly charges, NLB costs, and data processing fees Service endpoints are strictly Region-specific; must create endpoints in each Region where access is needed
S3 Access Points S3, IAM, VPC (for VPC-specific access points)
  • Dedicated IAM policies per access point
  • VPC-only access restrictions available
  • Works with bucket policies for layered security
  • Supports AWS PrivateLink for private network access
  • Compatible with S3 Block Public Access settings
  • No additional charge for S3 Access Points
  • Standard S3 request pricing applies
  • Data transfer fees apply based on standard S3 rates
  • VPC endpoint charges apply when using VPC endpoints with access points
  • Access points are Region-specific
  • Each access point is created in the same Region as its S3 bucket
  • Cross-Region access requires separate access points in each Region
  • VPC-specific access points are limited to the VPC’s Region

* Pricing information provided is based on AWS service rates at the time of publication and is intended as an estimation only. Additional costs may be incurred depending on your specific implementation and usage patterns. For the most current and accurate pricing details, please consult the official AWS pricing pages for each service mentioned.

Let’s examine the solutions in detail.

AWS Transfer Family

AWS Transfer Family is a managed file transfer service for SFTP, FTPS, and AS2 protocols. It integrates directly with Amazon Simple Storage Service (Amazon S3) for storage and supports custom identity providers for authentication through Amazon API Gateway and AWS Lambda.

As shown in Figure 1, when a user initiates a file transfer, Transfer Family authenticates them through the configured identity provider using API Gateway and Lambda. After authentication succeeds, the service maps the user to an AWS Identity and Access Management (IAM) role that defines their S3 bucket access permissions. The service encrypts data in transit using TLS 1.2 and data at rest using S3 server-side encryption.

Figure 1: AWS Transfer Family architecture

Figure 1: AWS Transfer Family architecture

Transfer Family automatically handles scaling from zero to thousands of concurrent users, manages high availability across Availability Zones, and minimizes infrastructure management. It records detailed metrics and logs in Amazon CloudWatch for monitoring and auditing, supporting compliance requirements with activity tracking.

It’s important to note that Transfer Family also offers service-managed authentication. This simpler setup stores user credentials (passwords or SSH keys) directly in Transfer Family, minimizing the need for external identity providers. Service-managed authentication is best suited if you have a small number of users or no existing identity management system, or when you want to have a disconnected identity system and don’t want to give external partners an account in your identity provider system.

Pros

One of the biggest advantages of Transfer Family is how it provides the reliability and scalability of Amazon S3 for storing your data, while keeping that data available to existing client applications and workflows. The service integrates with existing authentication systems through custom identity providers, while maintaining security through IAM policies. Its auto-scaling capabilities handle variable workloads, from occasional transfers to high-volume scenarios.

Transfer Family also offers detailed CloudWatch logging and audit trails for file transfer activities, which should be sufficient for most logging and audit needs. It encrypts data in transit using TLS 1.2 and at rest using Amazon S3 server-side encryption. You can implement fine-grained access controls through IAM roles and integrate with AWS Organizations for multi-account management. The service supports VPC endpoints for secure internal access and custom domain names for branded endpoints.

Because data is stored in S3, some of your requirements will be fulfilled by configuring S3, not the Transfer Family services. Data retention (for example, avoiding deletion and scheduling deletion) is achieved through S3 Object Lock and S3 Lifecycle Events.

Cons

The pricing structure of Transfer Family includes $0.30 per hour for each protocol you enable and data transfer fees based on data volume. There can be additional charges for custom domain names. If you use VPC endpoints for secure internal access to Amazon S3, there will also be VPC data charges. If you have high-volume transfers or multiple endpoints across AWS Regions, you will face increased costs. Because the data ultimately lives in S3; S3 storage and request pricing applies as well.

Custom identity provider implementations (such as SAML or OAuth) add latency to authentication processes, affecting transfer initiation times. This authentication process requires additional configuration and introduces extra steps and latency during transfer initiation compared to service-managed authentication.

The Regional nature of Transfer Family means you must choose between deploying in a single Region (simpler management but potential latency for global users) or multiple Regions (better performance but higher costs at $0.30 per protocol per hour per Region). Multi-Region can serve as a disaster recovery strategy or when Regional data isolation is needed.

Transfer Family web apps

Transfer Family web apps provide browser-based access to Amazon S3, enabling users to upload and download files through a web interface. With the web apps, you can create a branded, secure, and highly available portal for your users to browse, upload, and download data in S3. Web apps are built using Storage Browser for S3 and offer the same user functionalities in a fully managed offering without having to write code or host your own application.

When a user accesses the web application, authentication occurs through AWS IAM Identity Center, and S3 Access Grants determine their permissions to specific S3 buckets or prefixes. The access grant permissions can be either read-only or read and write. After authentication succeeds, users can upload or download files directly through the web interface. The service uses Amazon CloudFront for content delivery and implements SSL/TLS encryption for data transfers, while S3 provides server-side encryption for data at rest. Figure 2 shows a simplified Transfer Family web app architecture.

Figure 2: Simplified Transfer Family web app architecture

Figure 2: Simplified Transfer Family web app architecture

The web application automatically scales to accommodate varying numbers of users and provides high availability through the CloudFront global edge network. It minimizes the need for custom web application development and provides logging through AWS CloudTrail and CloudWatch. You can customize the user experience by implementing custom domains through CloudFront distributions.

Transfer Family web apps support multiple authentication methods, with IAM Identity Center being one of the primary options. While Identity Center provides simplified user management and integration with existing identity providers. It also provides useful mechanisms such as multi-factor authentication (MFA), strong password policies, and resetting lost passwords. It’s not the only authentication method available; you can also use custom identity providers for authentication, providing flexibility in how you manage user access to the web application.

Pros

Transfer Family web apps minimize the need to build and maintain custom web interfaces for Amazon S3 file sharing. It provides seamless integration with IAM Identity Center for user management and authentication, enabling you to use existing identity providers. The service offers fine-grained access control through S3 Access Grants, allowing precise permission management at the bucket and prefix level. Its integration with CloudFront provides global availability and enhanced performance, while CloudTrail logging offers audit capabilities.

The service provides robust security features including SSL/TLS encryption, CORS policy management, and optional integration with AWS WAF for protection against bots, web scrapers, DDoS events, and more. You can implement custom domains for branded experiences and use CloudFront security features including DDoS protection using AWS Shield. The web interface offers intuitive file management capabilities without requiring client software or that users have technical expertise.

Cons

Transfer Family web apps require using IAM Identity Center, which might require additional setup and configuration if you’re not currently using this service. The web interface currently requires the Identity Center identities to live in the same AWS account as the S3 buckets. That might create design challenges if you want to keep identities in one AWS account and data storage in another. Implementation requires careful cross-origin resource sharing (CORS) configuration for each S3 bucket.

The service incurs costs for both Transfer Family and associated services, including CloudFront distribution and data transfer fees. Custom domain implementation requires additional configuration and SSL certificate management through AWS Certificate Manager (ACM). The web interface is well suited for humans to upload or download, but it’s not as good for automated workflows that transfer files from machine to machine. You must carefully manage user assignments and access grants to maintain security, adding administrative overhead.

S3 pre-signed URLs

Amazon S3 pre-signed URLs enable secure, time-limited access to objects in S3 without requiring the file recipient to have an identity in your identity systems. The URLs are generated using the AWS SDK or AWS Command Line Interface (AWS CLI), granting specific permissions (GET, PUT) that are valid for up to seven days. When accessing files, S3 validates the cryptographically signed parameters in these URLs before permitting access to objects. This provides a direct method for secure file sharing through HTTPS endpoints.

The solution requires only an S3 bucket and appropriate IAM permissions for URL generation. S3 handles the authentication of the pre-signed URL parameters and manages access to objects. File transfers occur directly between users and S3 through HTTPS endpoints, with the pre-signed URL controlling the access patterns.

Amazon S3 provides security features including server-side encryption, access logging, and CloudTrail integration. The security of pre-signed URLs is primarily managed through expiration times and specific operation permissions defined during URL generation.

Pros

Amazon S3 pre-signed URLs follow a straightforward pay-per-use pricing model, charging only for S3 storage, requests, and data transfers. For example, if you create pre-signed URLs but the object isn’t actually downloaded, you pay storage costs as usual, but you don’t pay transfer costs. The solution uses the native scalability of S3 to handle varying numbers of concurrent users without additional infrastructure. you can implement granular access controls through URL expiration times and specific operation permissions (GET, PUT, DELETE).

Access is controlled through URL expiration enforcement. Amazon S3 server access logging and CloudTrail integration enable audit capabilities. The solution’s simplicity makes it ideal for basic file sharing needs while maintaining security and scalability.

Cons

A pre-signed URL can be used by anyone who has access to the URL. That’s the goal of this design: You don’t need to have an identity for the user. Pre-signed URLs can be reused an unlimited number of times until they expire. To improve security, short expiration times can limit the potential for URL re-use. Shorter expiration times, however, require the recipient to download the file soon after the URL is created.

When implementing this solution, you should establish processes for secure URL generation and distribution. Set your URL expiration times based on realistic expectations about how quickly your recipients will download the files. A web or mobile app where the user selects a link to download something (such as a document, an image, a data file) and they expect the download to start immediately is a good candidate for this design.

The solution works with files up to 5 GB for single operations. To share a file larger than 5 GB, you must split the file into multiple parts, issue multiple pre-signed URLs, and then the recipient must download all the parts and join the parts together correctly. This isn’t a good solution for sharing large files. Also, distributing large files as a single download can be difficult if the recipient doesn’t have good connectivity. Amazon S3 can start an object download from the middle of the object, but selecting a pre-signed URL cannot. So, if the recipient transfers 1 GB out of a 2 GB download, and then their connection is disrupted, they cannot pick up where they left off. They will restart from the beginning, which is undesirable. Overall, this design is unsuitable for transmitting large files over unreliable internet connections.

You should enable appropriate monitoring through Amazon S3 access logs and CloudTrail to track usage patterns and meet security compliance.

This solution is particularly effective if you’re seeking straightforward, secure file sharing capabilities where the files are small enough to download in one request, and where you have a secure mechanism to share the download URLs.

Serverless web application with S3 presigned URLs

Amazon S3 presigned URLs combined with a custom web application enable secure, time-limited access to S3 objects. The application generates URLs that grant specific S3 permissions (GET, PUT) for between one minute and seven days. When requesting file access, the application authenticates users and generates presigned URLs using the AWS SDK with defined permissions and expiration times.

The web application uses API Gateway and Lambda functions for authentication and URL generation. Amazon S3 validates the cryptographically signed parameters in these URLs before permitting access to objects. File transfers occur directly between users and S3 through HTTPS endpoints, with the application controlling the access patterns. The architecture is shown in Figure 3.

Figure 3: Amazon S3 pre-signed URLs architecture

Figure 3: Amazon S3 pre-signed URLs architecture

The web application can implement security controls including request logging, rate limiting (requests per second), and authentication workflows. CloudWatch logs record API access patterns and Lambda execution metrics, while Amazon S3 access logging records object-level operations.

Pros

Amazon S3 presigned URLs follow a pay-per-use pricing model. This solution charges only for API Gateway requests, Lambda executions, and S3 operations performed. The serverless architecture scales automatically from zero to thousands of concurrent users without infrastructure management. You can implement custom security controls and business logic for specific access requirements through API Gateway authorizers (using custom identity solutions or Amazon Cognito) and Lambda functions.

The solution enforces security through URL expiration (maximum seven days), IAM policies restricting URL generation permissions, and HTTPS encryption for data transfers. Custom authentication workflows integrate with existing identity providers (SAML, OIDC). Additional security features include IP-based restrictions, required request headers, and request validation through AWS WAF. This solution would be good, for example, if you have a variety of files or a variety of buckets and you’re trying to build a unified front-end where people can download various files without knowing which bucket the files are stored in or what URL expiration time is appropriate. You can configure the frontend to look at tags on objects, tags on buckets, object names, or another attribute that fits your use case, and then choose a URL expiration time based on that attribute. For example, objects from buckets tagged Data Classification: Restricted might expire after 1 minute, whereas objects from buckets tagged Data Classification: Public might be valid for 7 days.

Cons

Building a custom web application requires developing and maintaining the code for URL generation, authentication, and error handling logic. The application must track URL expiration times and implement mechanisms that permit retries for failed transfers. Monitoring systems must track URL usage, detect abuse patterns, and send alerts for security violations through CloudWatch metrics and logs.

One limitation of this solution is the 10 MB size limit imposed by API Gateway. This affects how your application handles file uploads and downloads. For uploads, files under 10 MB can be uploaded directly through API Gateway. Larger files require implementing multipart uploads, where the client splits the file into chunks and sends each chunk separately. For downloads, files under 10 MB can be downloaded directly through API Gateway but for larger files, your application should generate a pre-signed URL for direct Amazon S3 access, bypassing API Gateway.

URL generation errors or misconfigured IAM permissions can expose objects to unauthorized access. The HTTPS-only protocol limits integration with SFTP and FTPS clients. Files larger than 5 GB require multipart upload implementation, and network interruptions need custom resume logic. This design will incur some extra charges if the number of file transfers are the millions. Lambda functions cost $0.20 per million requests, and API Gateway costs $1.00 per million requests. Analyze your expected access patterns to determine whether these extra costs will be significant and if they’re worth the additional flexibility of custom transfer logic.

Decision matrix: When to use each solution

The following table summarizes the characteristics of the solutions presented in the two parts of this post. See Part 2 for full descriptions of the solutions not covered in Part 1.

Characteristics Transfer Family Transfer Family web app S3 pre-signed URLs (Direct) Serverless web application with S3 pre-signed URL CloudFront signed URLs (Part 2) VPC endpoint service (Part 2) S3 Object Lambda (Part 2)
Protocol support SFTP, FTPS, and AS2 HTTPS (web-based) HTTPS HTTPS HTTPS with CDN A TCP-based protocol HTTPS
Global distribution Global endpoint support CloudFront integration Global S3 access Global S3 access Global edge network acceleration Direct AWS backbone access Global S3 access with Regional endpoints
Pricing model Hourly service rate and usage Pay per file operation Pay-per-request Pay-per-request and application costs Pay-per-request with caching savings Hourly endpoint rate and usage No additional charge for access points; standard S3 request pricing applies
Content processing Direct S3 integration Built-in web interface Direct S3 access Custom app processing Edge-based file processing Access files through private network Direct S3 access with customized permissions per access point
Authentication options Custom IdP and service-managed IAM Identity Center IAM Custom authentication possible IAM, custom authentication, and edge validation VPC security controls and custom authentication IAM policies, VPC endpoint policies, resource-based policies
Upload capabilities Unlimited file size Web interface upload Up to 5 GB direct and multipart for larger Up to 10 MB using API Gateway Optimized for global ingestion Unlimited file size over private connection Same as standard S3
Download capabilities Unlimited file size Browser-based downloads Up to 5 GB using a single URL Up to 10 MB using API Gateway Accelerated downloads using global edge locations Unlimited file size over private connection Same as standard S3 with customized access controls
Example use cases
  • Enterprise file transfer systems
  • B2B data exchange
  • Compliance-focused transfers
  • Browser-based file sharing
  • Internal document management
  • Client portals
  • Simple direct S3 access
  • Temporary file sharing
  • Mobile app backend
  • Custom file sharing systems
  • Integrated web applications
  • Enhanced S3 access control
  • Global content delivery
  • Media distribution
  • Web application assets
  • Private network transfers
  • Custom protocol support
  • Secure enterprise data exchange
  • Simplified data access management at scale
  • Multi-application access to shared datasets
  • VPC-restricted data access

The following list gives you a quick overview of the strengths of each solution presented in the two parts of this post.

  • Transfer Family is the optimal choice for organizations that require legacy file transfer protocols such as SFTP, FTPS, or AS2 protocols, and you must integrate with existing authentication systems. It’s ideal for scenarios with strict compliance and audit requirements, where operational overhead needs to be minimized. While the solution comes with higher costs because of its managed service nature, it’s often the lowest-friction option to support existing enterprise use cases that depend on these protocols.
  • Transfer Family web apps suit organizations that need browser-based file sharing without custom development. They integrate with IAM Identity Center for user authentication and uses Amazon S3 Access Grants for permission management. The solution works well for internal document sharing, client portals, and scenarios requiring a branded web interface. While limited to web browser access, they provide built-in features like MFA and password management without infrastructure maintenance.
  • Amazon S3 pre-signed URLs excel in scenarios where simplicity, cost-effectiveness, and temporary access are key requirements. This solution is ideal if you’re seeking a straightforward file sharing mechanism without the need for custom application development or additional infrastructure. This approach shines in environments that require a quick implementation of secure file sharing and cost-effective solutions with minimal overhead.
  • Serverless web application with S3 presigned URLs best serves scenarios where cost optimization is paramount and the HTTPS protocol meets your requirements. This solution shines in environments that need simple, direct file sharing capabilities with quick implementation timelines. It’s particularly effective for moderate usage patterns where serverless architecture can provide cost benefits. The solution’s simplicity makes it ideal for web applications and scenarios where complex file transfer protocols aren’t necessary, though careful consideration must be given to its 10 MB file size limitation for single operations using API Gateway.

In Part 2:

  • CloudFront signed URLs excel in situations that demand global content distribution with high performance requirements. This solution is the clear choice when your architecture needs built-in DDoS protection and performance optimization through caching. It’s particularly valuable when content delivery speed is crucial and you require security at edge locations. The solution’s global reach and caching capabilities make it cost-effective for large-scale content distribution, though it’s primarily optimized for download scenarios rather than uploads.
  • Amazon VPC endpoint service is the preferred choice if you require complete network isolation and maximum security. This solution is ideal when you need support for custom protocols while maintaining private network connectivity. It’s particularly suitable for scenarios with extremely high security requirements and when you have the necessary resources to managed networking configurations. While this solution requires significant expertise and investment, it provides the highest level of security and control for sensitive data transfers.
  • S3 Access Points are best suited for scenarios that require simplified data access management at scale. This solution excels when you need to provide different access patterns to the same underlying data for multiple applications or user groups. It’s ideal if you prefer a structured approach to permissions and need network-level access controls. While primarily focused on simplifying complex access scenarios without modifying bucket policies, it offers unique capabilities for VPC-restricted access and granular permissions management, though subject to certain service limits and configuration requirements.

Conclusion

In this first part of a two-part post, you’ve learned about multiple solutions for secure file sharing using AWS services and the pros and cons of each. You can find additional options in Part 2. The optimal solution depends on your specific organizational requirements, technical capabilities, and budget constraints. You don’t have to choose just one option, you can implement multiple solutions to address different use cases, creating a file sharing strategy that balances security, cost, and operational efficiency.

Additional resources:

If you have feedback about this post, submit comments in the Comments section below.
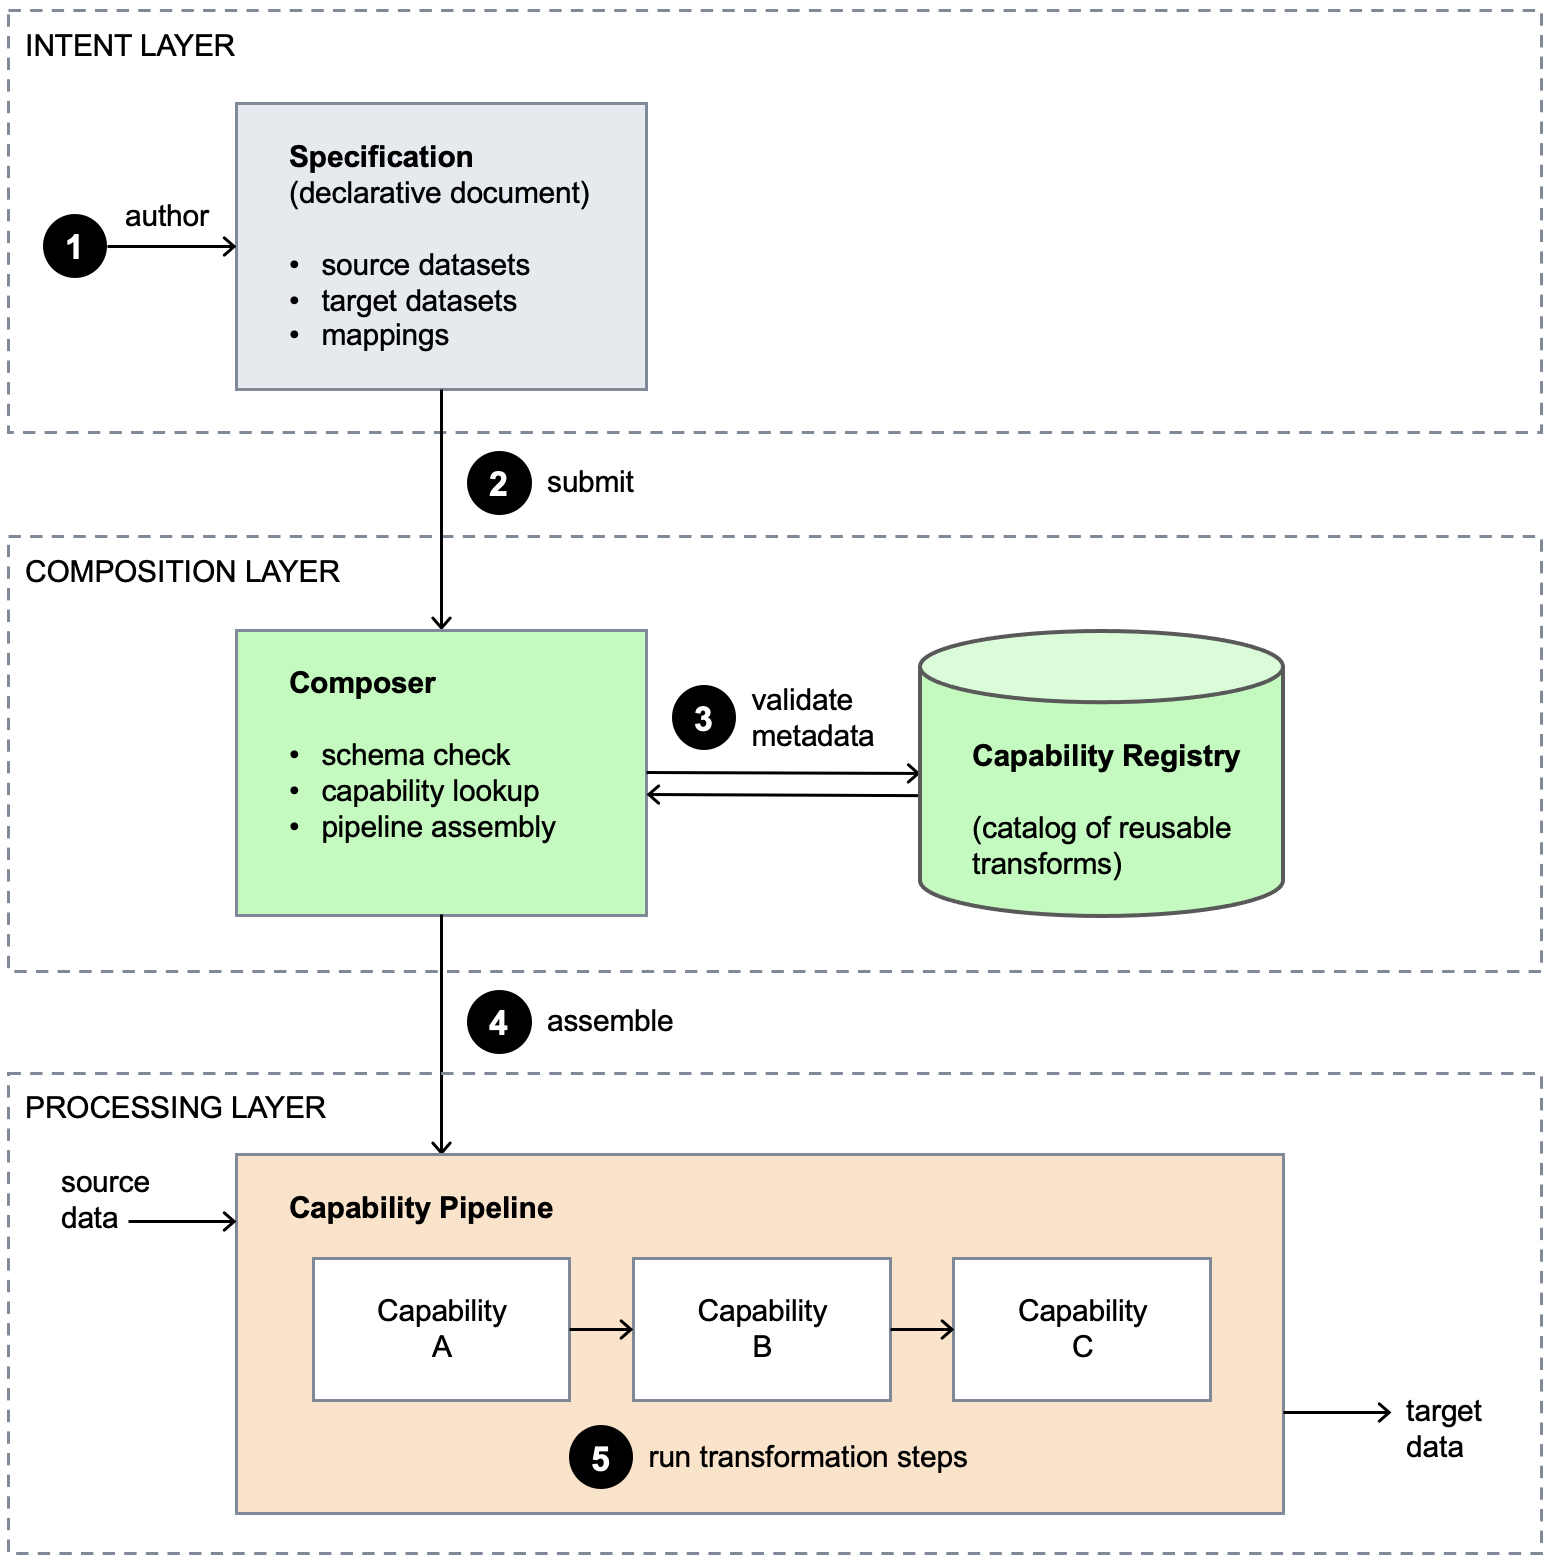
Swapnil Singh

Swapnil Singh

Swapnil is a Senior Solutions Architect for AWS World Wide Public Sector. As a Product Acceleration Solutions Architect at AWS, she currently works with GovTech customers to ideate, design, validate, and launch products using cloud-native technologies and modern development practices.

Sumit Bhati

Sumit Bhati

Sumit is a Senior Customer Solutions Manager at AWS, specializing in expediting the cloud journey for enterprise customers. Sumit is dedicated to assisting customers through every phase of their cloud adoption, from accelerating migrations to modernizing workloads and facilitating the integration of innovative practices.

Enhance container software supply chain visibility through SBOM export with Amazon Inspector and QuickSight

Post Syndicated from Jason Ng original https://aws.amazon.com/blogs/security/enhance-container-software-supply-chain-visibility-through-sbom-export-with-amazon-inspector-and-quicksight/

In this post, I’ll show how you can export software bills of materials (SBOMs) for your containers by using an AWS native service, Amazon Inspector, and visualize the SBOMs through Amazon QuickSight, providing a single-pane-of-glass view of your organization’s software supply chain.

The concept of a bill of materials (BOM) originated in the manufacturing industry in the early 1960s. It was used to keep track of the quantities of each material used to manufacture a completed product. If parts were found to be defective, engineers could then use the BOM to identify products that contained those parts. An SBOM extends this concept to software development, allowing engineers to keep track of vulnerable software packages and quickly remediate the vulnerabilities.

Today, most software includes open source components. A Synopsys study, Walking the Line: GitOps and Shift Left Security, shows that 8 in 10 organizations reported using open source software in their applications. Consider a scenario in which you specify an open source base image in your Dockerfile but don’t know what packages it contains. Although this practice can significantly improve developer productivity and efficiency, the decreased visibility makes it more difficult for your organization to manage risk effectively.

It’s important to track the software components and their versions that you use in your applications, because a single affected component used across multiple organizations could result in a major security impact. According to a Gartner report titled Gartner Report for SBOMs: Key Takeaways You Should know, by 2025, 60 percent of organizations building or procuring critical infrastructure software will mandate and standardize SBOMs in their software engineering practice, up from less than 20 percent in 2022. This will help provide much-needed visibility into software supply chain security.

Integrating SBOM workflows into the software development life cycle is just the first step—visualizing SBOMs and being able to search through them quickly is the next step. This post describes how to process the generated SBOMs and visualize them with Amazon QuickSight. AWS also recently added SBOM export capability in Amazon Inspector, which offers the ability to export SBOMs for Amazon Inspector monitored resources, including container images.

Why is vulnerability scanning not enough?

Scanning and monitoring vulnerable components that pose cybersecurity risks is known as vulnerability scanning, and is fundamental to organizations for ensuring a strong and solid security posture. Scanners usually rely on a database of known vulnerabilities, the most common being the Common Vulnerabilities and Exposures (CVE) database.

Identifying vulnerable components with a scanner can prevent an engineer from deploying affected applications into production. You can embed scanning into your continuous integration and continuous delivery (CI/CD) pipelines so that images with known vulnerabilities don’t get pushed into your image repository. However, what if a new vulnerability is discovered but has not been added to the CVE records yet? A good example of this is the Apache Log4j vulnerability, which was first disclosed on Nov 24, 2021 and only added as a CVE on Dec 1, 2021. This means that for 7 days, scanners that relied on the CVE system weren’t able to identify affected components within their organizations. This issue is known as a zero-day vulnerability. Being able to quickly identify vulnerable software components in your applications in such situations would allow you to assess the risk and come up with a mitigation plan without waiting for a vendor or supplier to provide a patch.

In addition, it’s also good hygiene for your organization to track usage of software packages, which provides visibility into your software supply chain. This can improve collaboration between developers, operations, and security teams, because they’ll have a common view of every software component and can collaborate effectively to address security threats.

In this post, I present a solution that uses the new Amazon Inspector feature to export SBOMs from container images, process them, and visualize the data in QuickSight. This gives you the ability to search through your software inventory on a dashboard and to use natural language queries through QuickSight Q, in order to look for vulnerabilities.

Solution overview

Figure 1 shows the architecture of the solution. It is fully serverless, meaning there is no underlying infrastructure you need to manage. This post uses a newly released feature within Amazon Inspector that provides the ability to export a consolidated SBOM for Amazon Inspector monitored resources across your organization in commonly used formats, including CycloneDx and SPDX.

Figure 1: Solution architecture diagram

Figure 1: Solution architecture diagram

The workflow in Figure 1 is as follows:

  1. The image is pushed into Amazon Elastic Container Registry (Amazon ECR), which sends an Amazon EventBridge event.
  2. This invokes an AWS Lambda function, which starts the SBOM generation job for the specific image.
  3. When the job completes, Amazon Inspector deposits the SBOM file in an Amazon Simple Storage Service (Amazon S3) bucket.
  4. Another Lambda function is invoked whenever a new JSON file is deposited. The function performs the data transformation steps and uploads the new file into a new S3 bucket.
  5. Amazon Athena is then used to perform preliminary data exploration.
  6. A dashboard on Amazon QuickSight displays SBOM data.

Implement the solution

This section describes how to deploy the solution architecture.

In this post, you’ll perform the following tasks:

  • Create S3 buckets and AWS KMS keys to store the SBOMs
  • Create an Amazon Elastic Container Registry (Amazon ECR) repository
  • Deploy two AWS Lambda functions to initiate the SBOM generation and transformation
  • Set up Amazon EventBridge rules to invoke Lambda functions upon image push into Amazon ECR
  • Run AWS Glue crawlers to crawl the transformed SBOM S3 bucket
  • Run Amazon Athena queries to review SBOM data
  • Create QuickSight dashboards to identify libraries and packages
  • Use QuickSight Q to identify libraries and packages by using natural language queries

Deploy the CloudFormation stack

The AWS CloudFormation template we’ve provided provisions the S3 buckets that are required for the storage of raw SBOMs and transformed SBOMs, the Lambda functions necessary to initiate and process the SBOMs, and EventBridge rules to run the Lambda functions based on certain events. An empty repository is provisioned as part of the stack, but you can also use your own repository.

To deploy the CloudFormation stack

  1. Download the CloudFormation template.
  2. Browse to the CloudFormation service in your AWS account and choose Create Stack.
  3. Upload the CloudFormation template you downloaded earlier.
  4. For the next step, Specify stack details, enter a stack name.
  5. You can keep the default value of sbom-inspector for EnvironmentName.
  6. Specify the Amazon Resource Name (ARN) of the user or role to be the admin for the KMS key.
  7. Deploy the stack.

Set up Amazon Inspector

If this is the first time you’re using Amazon Inspector, you need to activate the service. In the Getting started with Amazon Inspector topic in the Amazon Inspector User Guide, follow Step 1 to activate the service. This will take some time to complete.

Figure 2: Activate Amazon Inspector

Figure 2: Activate Amazon Inspector

SBOM invocation and processing Lambda functions

This solution uses two Lambda functions written in Python to perform the invocation task and the transformation task.

  • Invocation task — This function is run whenever a new image is pushed into Amazon ECR. It takes in the repository name and image tag variables and passes those into the create_sbom_export function in the SPDX format. This prevents duplicated SBOMs, which helps to keep the S3 data size small.
  • Transformation task — This function is run whenever a new file with the suffix .json is added to the raw S3 bucket. It creates two files, as follows:
    1. It extracts information such as image ARN, account number, package, package version, operating system, and SHA from the SBOM and exports this data to the transformed S3 bucket under a folder named sbom/.
    2. Because each package can have more than one CVE, this function also extracts the CVE from each package and stores it in the same bucket in a directory named cve/. Both files are exported in Apache Parquet so that the file is in a format that is optimized for queries by Amazon Athena.

Populate the AWS Glue Data Catalog

To populate the AWS Glue Data Catalog, you need to generate the SBOM files by using the Lambda functions that were created earlier.

To populate the AWS Glue Data Catalog

  1. You can use an existing image, or you can continue on to create a sample image.
  2. Open an AWS Cloudshell terminal.
  3. Run the follow commands
    # Pull the nginx image from a public repo
    docker pull public.ecr.aws/nginx/nginx:1.19.10-alpine-perl
    
    docker tag public.ecr.aws/nginx/nginx:1.19.10-alpine-perl <ACCOUNT-ID>.dkr.ecr.us-east-1.amazonaws.com/sbom-inspector:nginxperl
    
    # Authenticate to ECR, fill in your account id
    aws ecr get-login-password --region us-east-1 | docker login --username AWS --password-stdin <ACCOUNT-ID>.dkr.ecr.us-east-1.amazonaws.com
    
    # Push the image into ECR
    docker push <ACCOUNT-ID>.dkr.ecr.us-east-1.amazonaws.com/sbom-inspector:nginxperl

  4. An image is pushed into the Amazon ECR repository in your account. This invokes the Lambda functions that perform the SBOM export by using Amazon Inspector and converts the SBOM file to Parquet.
  5. Verify that the Parquet files are in the transformed S3 bucket:
    1. Browse to the S3 console and choose the bucket named sbom-inspector-<ACCOUNT-ID>-transformed. You can also track the invocation of each Lambda function in the Amazon CloudWatch log console.
    2. After the transformation step is complete, you will see two folders (cve/ and sbom/)in the transformed S3 bucket. Choose the sbom folder. You will see the transformed Parquet file in it. If there are CVEs present, a similar file will appear in the cve folder.

    The next step is to run an AWS Glue crawler to determine the format, schema, and associated properties of the raw data. You will need to crawl both folders in the transformed S3 bucket and store the schema in separate tables in the AWS Glue Data Catalog.

  6. On the AWS Glue Service console, on the left navigation menu, choose Crawlers.
  7. On the Crawlers page, choose Create crawler. This starts a series of pages that prompt you for the crawler details.
  8. In the Crawler name field, enter sbom-crawler, and then choose Next.
  9. Under Data sources, select Add a data source.
  10. Now you need to point the crawler to your data. On the Add data source page, choose the Amazon S3 data store. This solution in this post doesn’t use a connection, so leave the Connection field blank if it’s visible.
  11. For the option Location of S3 data, choose In this account. Then, for S3 path, enter the path where the crawler can find the sbom and cve data, which is s3://sbom-inspector-<ACCOUNT-ID>-transformed/sbom/ and s3://sbom-inspector-<ACCOUNT-ID>-transformed/cve/. Leave the rest as default and select Add an S3 data source.
     
    Figure 3: Data source for AWS Glue crawler

    Figure 3: Data source for AWS Glue crawler

  12. The crawler needs permissions to access the data store and create objects in the Data Catalog. To configure these permissions, choose Create an IAM role. The AWS Identity and Access Management (IAM) role name starts with AWSGlueServiceRole-, and in the field, you enter the last part of the role name. Enter sbomcrawler, and then choose Next.
  13. Crawlers create tables in your Data Catalog. Tables are contained in a database in the Data Catalog. To create a database, choose Add database. In the pop-up window, enter sbom-db for the database name, and then choose Create.
  14. Verify the choices you made in the Add crawler wizard. If you see any mistakes, you can choose Back to return to previous pages and make changes. After you’ve reviewed the information, choose Finish to create the crawler.
    Figure 4: Creation of the AWS Glue crawler

    Figure 4: Creation of the AWS Glue crawler

  15. Select the newly created crawler and choose Run.
  16. After the crawler runs successfully, verify that the table is created and the data schema is populated.
     
    Figure 5: Table populated from the AWS Glue crawler

    Figure 5: Table populated from the AWS Glue crawler

Set up Amazon Athena

Amazon Athena performs the initial data exploration and validation. Athena is a serverless interactive analytics service built on open source frameworks that supports open-table and file formats. Athena provides a simplified, flexible way to analyze data in sources like Amazon S3 by using standard SQL queries. If you are SQL proficient, you can query the data source directly; however, not everyone is familiar with SQL. In this section, you run a sample query and initialize the service so that it can used in QuickSight later on.

To start using Amazon Athena

  1. In the AWS Management Console, navigate to the Athena console.
  2. For Database, select sbom-db (or select the database you created earlier in the crawler).
  3. Navigate to the Settings tab located at the top right corner of the console. For Query result location, select the Athena S3 bucket created from the CloudFormation template, sbom-inspector-<ACCOUNT-ID>-athena.
  4. Keep the defaults for the rest of the settings. You can now return to the Query Editor and start writing and running your queries on the sbom-db database.

You can use the following sample query.

select package, packageversion, cve, sha, imagearn from sbom
left join cve
using (sha, package, packageversion)
where cve is not null;

Your Athena console should look similar to the screenshot in Figure 6.

Figure 6: Sample query with Amazon Athena

Figure 6: Sample query with Amazon Athena

This query joins the two tables and selects only the packages with CVEs identified. Alternatively, you can choose to query for specific packages or identify the most common package used in your organization.

Sample output:

# package packageversion cve sha imagearn
<PACKAGE_NAME> <PACKAGE_VERSION> <CVE> <IMAGE_SHA> <ECR_IMAGE_ARN>

Visualize data with Amazon QuickSight

Amazon QuickSight is a serverless business intelligence service that is designed for the cloud. In this post, it serves as a dashboard that allows business users who are unfamiliar with SQL to identify zero-day vulnerabilities. This can also reduce the operational effort and time of having to look through several JSON documents to identify a single package across your image repositories. You can then share the dashboard across teams without having to share the underlying data.

QuickSight SPICE (Super-fast, Parallel, In-memory Calculation Engine) is an in-memory engine that QuickSight uses to perform advanced calculations. In a large organization where you could have millions of SBOM records stored in S3, importing your data into SPICE helps to reduce the time to process and serve the data. You can also use the feature to perform a scheduled refresh to obtain the latest data from S3.

QuickSight also has a feature called QuickSight Q. With QuickSightQ, you can use natural language to interact with your data. If this is the first time you are initializing QuickSight, subscribe to QuickSight and select Enterprise + Q. It will take roughly 20–30 minutes to initialize for the first time. Otherwise, if you are already using QuickSight, you will need to enable QuickSight Q by subscribing to it in the QuickSight console.

Finally, in QuickSight you can select different data sources, such as Amazon S3 and Athena, to create custom visualizations. In this post, we will use the two Athena tables as the data source to create a dashboard to keep track of the packages used in your organization and the resulting CVEs that come with them.

Prerequisites for setting up the QuickSight dashboard

This process will be used to create the QuickSight dashboard from a template already pre-provisioned through the command line interface (CLI). It also grants the necessary permissions for QuickSight to access the data source. You will need the following:

  • AWS Command Line Interface (AWS CLI) programmatic access with read and write permissions to QuickSight.
  • A QuickSight + Q subscription (only if you want to use the Q feature).
  • QuickSight permissions to Amazon S3 and Athena (enable these through the QuickSight security and permissions interface).
  • Set the default AWS Region where you want to deploy the QuickSight dashboard. This post assumes that you’re using the us-east-1 Region.

Create datasets

In QuickSight, create two datasets, one for the sbom table and another for the cve table.

  1. In the QuickSight console, select the Dataset tab.
  2. Choose Create dataset, and then select the Athena data source.
  3. Name the data source sbom and choose Create data source.
  4. Select the sbom table.
  5. Choose Visualize to complete the dataset creation. (Delete the analyses automatically created for you because you will create your own analyses afterwards.)
  6. Navigate back to the main QuickSight page and repeat steps 1–4 for the cve dataset.

Merge datasets

Next, merge the two datasets to create the combined dataset that you will use for the dashboard.

  1. On the Datasets tab, edit the sbom dataset and add the cve dataset.
  2. Set three join clauses, as follows:
    1. Sha : Sha
    2. Package : Package
    3. Packageversion : Packageversion
  3. Perform a left merge, which will append the cve ID to the package and package version in the sbom dataset.
     
    Figure 7: Combining the sbom and cve datasets

    Figure 7: Combining the sbom and cve datasets

Next, you will create a dashboard based on the combined sbom dataset.

Prepare configuration files

In your terminal, export the following variables. Substitute <QuickSight username> in the QS_USER_ARN variable with your own username, which can be found in the Amazon QuickSight console.

export ACCOUNT_ID=$(aws sts get-caller-identity --output text --query Account)
export TEMPLATE_ID=”sbom_dashboard”
export QS_USER_ARN=$(aws quicksight describe-user --aws-account-id $ACCOUNT_ID --namespace default --user-name <QuickSight username> | jq .User.Arn)
export QS_DATA_ARN=$(aws quicksight search-data-sets --aws-account-id $ACCOUNT_ID --filters Name="DATASET_NAME",Operator="StringLike",Value="sbom" | jq .DataSetSummaries[0].Arn)

Validate that the variables are set properly. This is required for you to move on to the next step; otherwise you will run into errors.

echo ACCOUNT_ID is $ACCOUNT_ID || echo ACCOUNT_ID is not set
echo TEMPLATE_ID is $TEMPLATE_ID || echo TEMPLATE_ID is not set
echo QUICKSIGHT USER ARN is $QS_USER_ARN || echo QUICKSIGHT USER ARN is not set
echo QUICKSIGHT DATA ARN is $QS_DATA_ARN || echo QUICKSIGHT DATA ARN is not set

Next, use the following commands to create the dashboard from a predefined template and create the IAM permissions needed for the user to view the QuickSight dashboard.

cat < ./dashboard.json
{
    "SourceTemplate": {
      "DataSetReferences": [
        {
          "DataSetPlaceholder": "sbom",
          "DataSetArn": $QS_DATA_ARN
        }
      ],
      "Arn": "arn:aws:quicksight:us-east-1:293424211206:template/sbom_qs_template"
    }
}
EOF

cat < ./dashboardpermissions.json
[
    {
      "Principal": $QS_USER_ARN,
      "Actions": [
        "quicksight:DescribeDashboard",
        "quicksight:ListDashboardVersions",
        "quicksight:UpdateDashboardPermissions",
        "quicksight:QueryDashboard",
        "quicksight:UpdateDashboard",
        "quicksight:DeleteDashboard",
        "quicksight:DescribeDashboardPermissions",
        "quicksight:UpdateDashboardPublishedVersion"
      ]
    }
]
EOF

Run the following commands to create the dashboard in your QuickSight console.

aws quicksight create-dashboard --aws-account-id $ACCOUNT_ID --dashboard-id $ACCOUNT_ID --name sbom-dashboard --source-entity file://dashboard.json

Note: Run the following describe-dashboard command, and confirm that the response contains a status code of 200. The 200-status code means that the dashboard exists.

aws quicksight describe-dashboard --aws-account-id $ACCOUNT_ID --dashboard-id $ACCOUNT_ID

Use the following update-dashboard-permissions AWS CLI command to grant the appropriate permissions to QuickSight users.

aws quicksight update-dashboard-permissions --aws-account-id $ACCOUNT_ID --dashboard-id $ACCOUNT_ID --grant-permissions file://dashboardpermissions.json

You should now be able to see the dashboard in your QuickSight console, similar to the one in Figure 8. It’s an interactive dashboard that shows you the number of vulnerable packages you have in your repositories and the specific CVEs that come with them. You can navigate to the specific image by selecting the CVE (middle right bar chart) or list images with a specific vulnerable package (bottom right bar chart).

Note: You won’t see the exact same graph as in Figure 8. It will change according to the image you pushed in.

Figure 8: QuickSight dashboard containing SBOM information

Figure 8: QuickSight dashboard containing SBOM information

Alternatively, you can use QuickSight Q to extract the same information from your dataset through natural language. You will need to create a topic and add the dataset you added earlier. For detailed information on how to create a topic, see the Amazon QuickSight User Guide. After QuickSight Q has completed indexing the dataset, you can start to ask questions about your data.

Figure 9: Natural language query with QuickSight Q

Figure 9: Natural language query with QuickSight Q

Conclusion

This post discussed how you can use Amazon Inspector to export SBOMs to improve software supply chain transparency. Container SBOM export should be part of your supply chain mitigation strategy and monitored in an automated manner at scale.

Although it is a good practice to generate SBOMs, it would provide little value if there was no further analysis being done on them. This solution enables you to visualize your SBOM data through a dashboard and natural language, providing better visibility into your security posture. Additionally, this solution is also entirely serverless, meaning there are no agents or sidecars to set up.

To learn more about exporting SBOMs with Amazon Inspector, see the Amazon Inspector User Guide.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
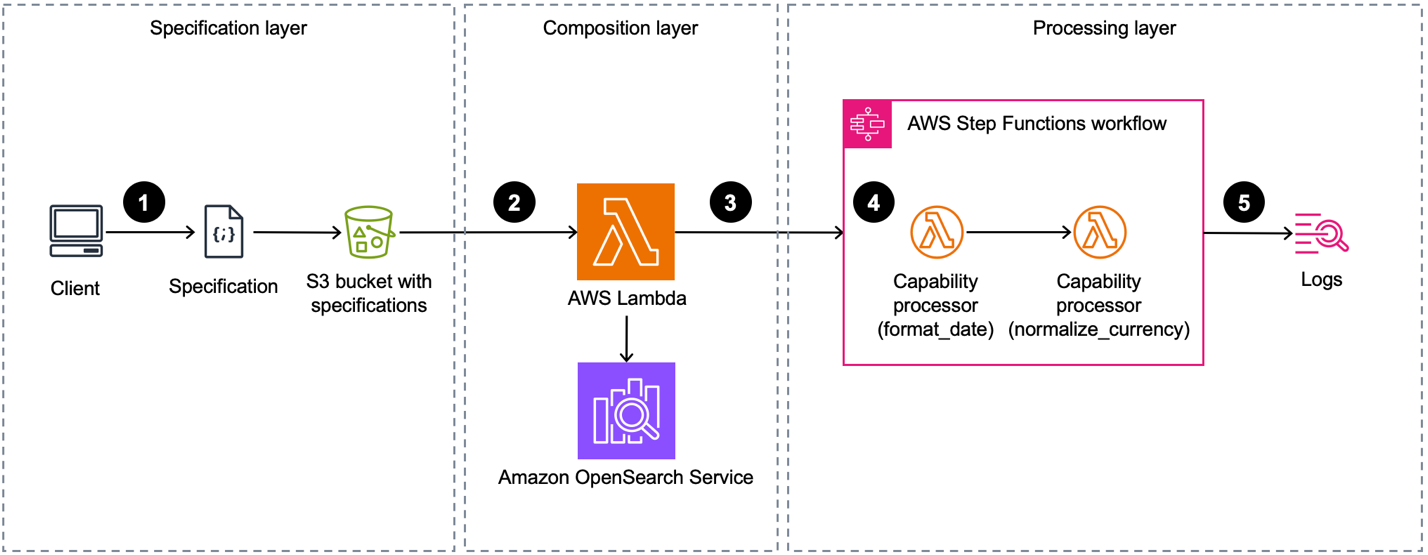
Jason Ng

Jason Ng

Jason is a Cloud Sales Center Solutions Architect at AWS. He works with enterprise and independent software vendor (ISV) greenfield customers in ASEAN countries and is part of the Containers Technical Field Community (TFC). He enjoys helping customers modernize their applications, drive growth, and reduce total cost of ownership.