The kernel’s swap subsystem is a complex and often unloved beast. It is
also a critical component in the memory-management subsystem and has a
significant impact on the performance of the system as a whole. At the
2025 Linux Storage, Filesystem, Memory-Management and BPF Summit, Kairui
Song outlined a plan to simplify and
optimize the kernel’s swap code. A first installment
of that work, written with help from Chris Li, was merged for the 6.18
release. This article will catch up with the 6.18 work, setting the stage
for a future look at the changes that are yet to be merged.
There’s a new report about two AI coding assistants, used by 1.5 million developers, that are surreptitiously sending a copy of everything they ingest to China.
It is finally time to start reviewing 5GbE products. To kick us off, we have the BrosTrend 5GbE adapter. This is enabled by the newer Realtek RTL8126 chip, and provides a relatively inexpensive way to step up from 1GbE networking. Pricing varies, but we purchased ours for under $35, which makes it quite reasonable. Since […]
Не знам дали има друг град като Пловдив в историята на Google, който може да постигне един и същ резил за втори път, но нека отново да предупредя, че пак сме се запътили натам. Този път съдя за това по косвени белези, защото (за щастие) се дистанцирах от тази болна тема, но нека да разясня заглавието на този текст.
Кризисният PR на община Пловдив никога не е бил особено талантлив и когато се разчу, че Google Maps повече няма да показва данни за тукашния градски транспорт и медиите разшумяха казуса, първоначалната реакция на местната власт беше да замаже положението. Първата глупост беше, че нямали договор с Google. Втората, че имали свое приложение. Пази боже!
Чак в третата идея имаше някакъв рационален елемент. Два месеца по-късно успяха да върнат данните за Пловдив в Google Maps. Даже беше представено като иновация от някои местни подлизурчести медии.
Тогава премълчах, но сега ще споделя и това. Бяха взели последния комплект данни, които ние от „Тракия Тех“ бяхме направили, като вероятно са ги пипнали тук-там, и ги бяха дали отново на Google като актуализирани данни.
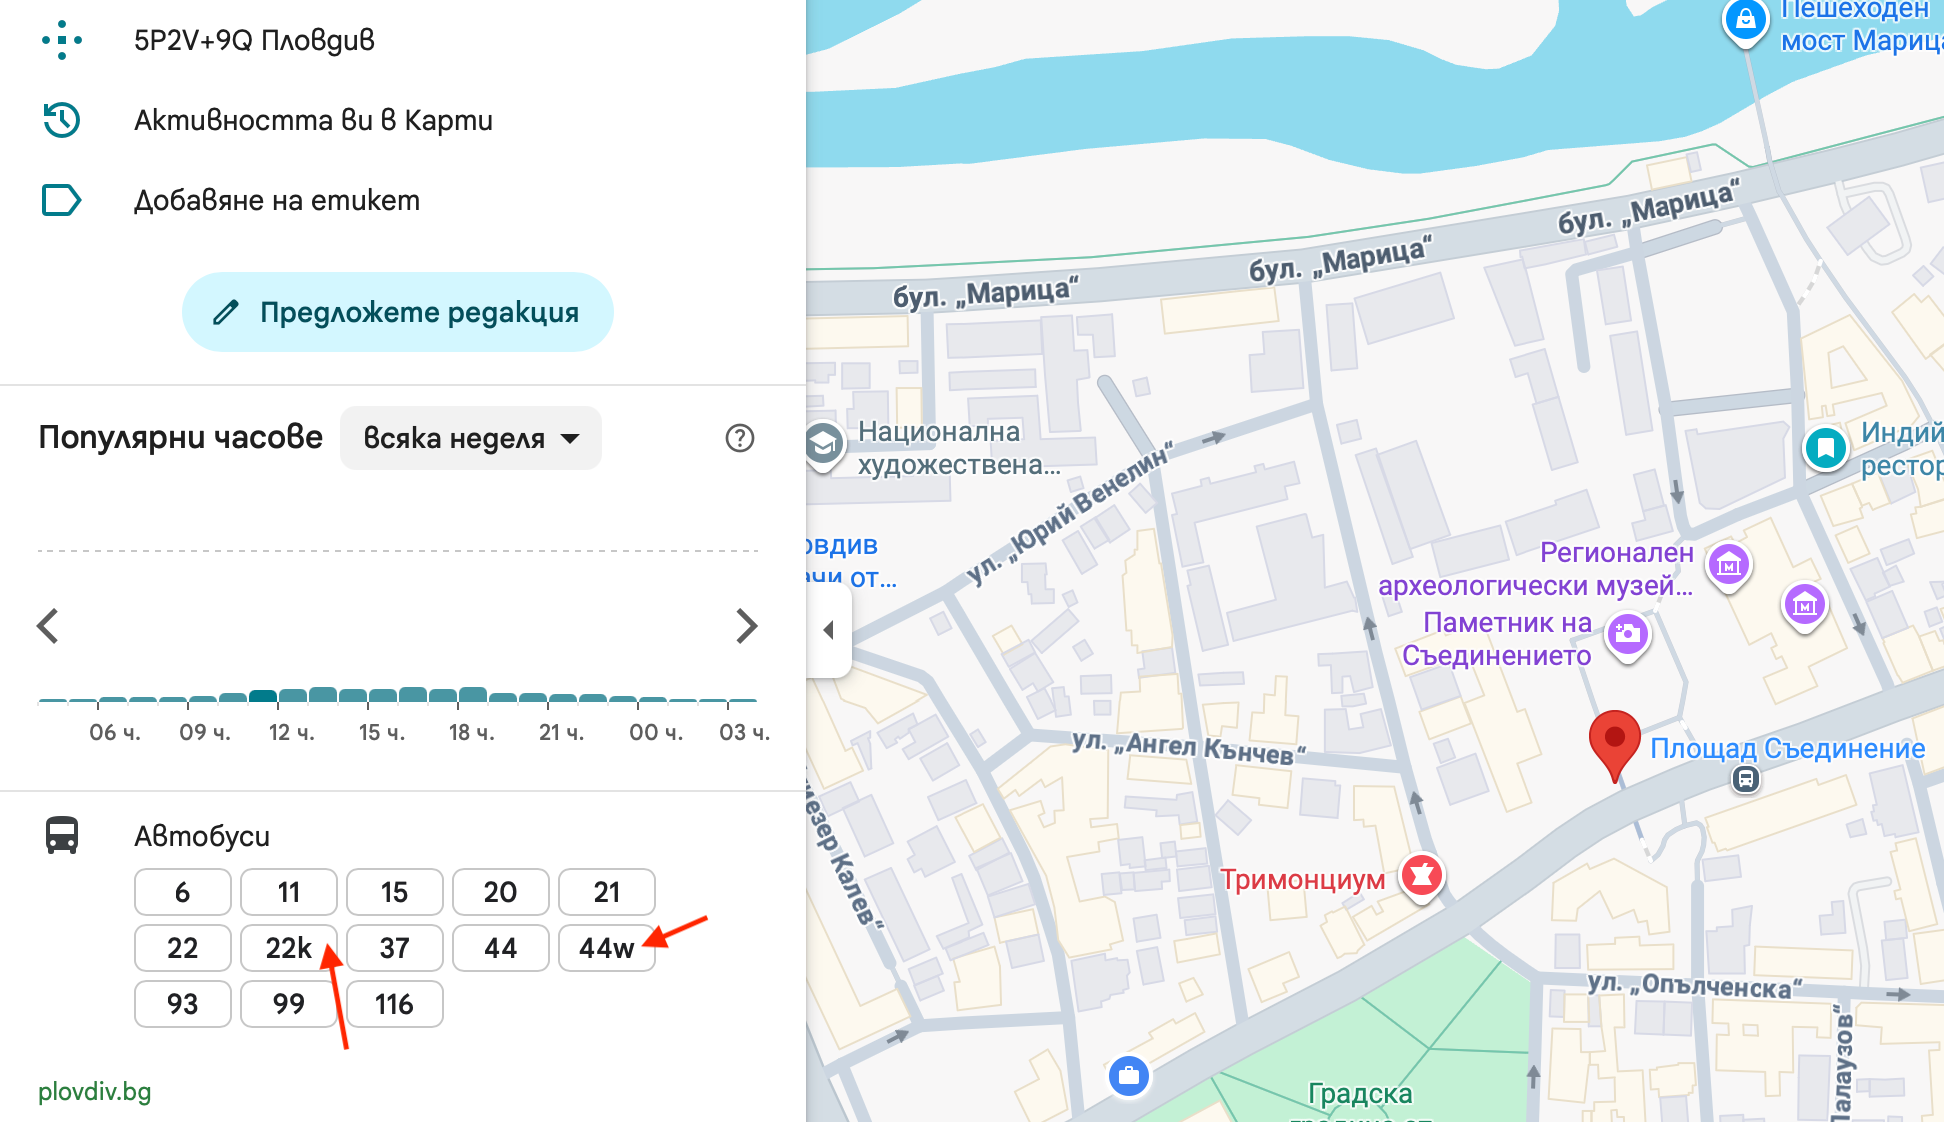
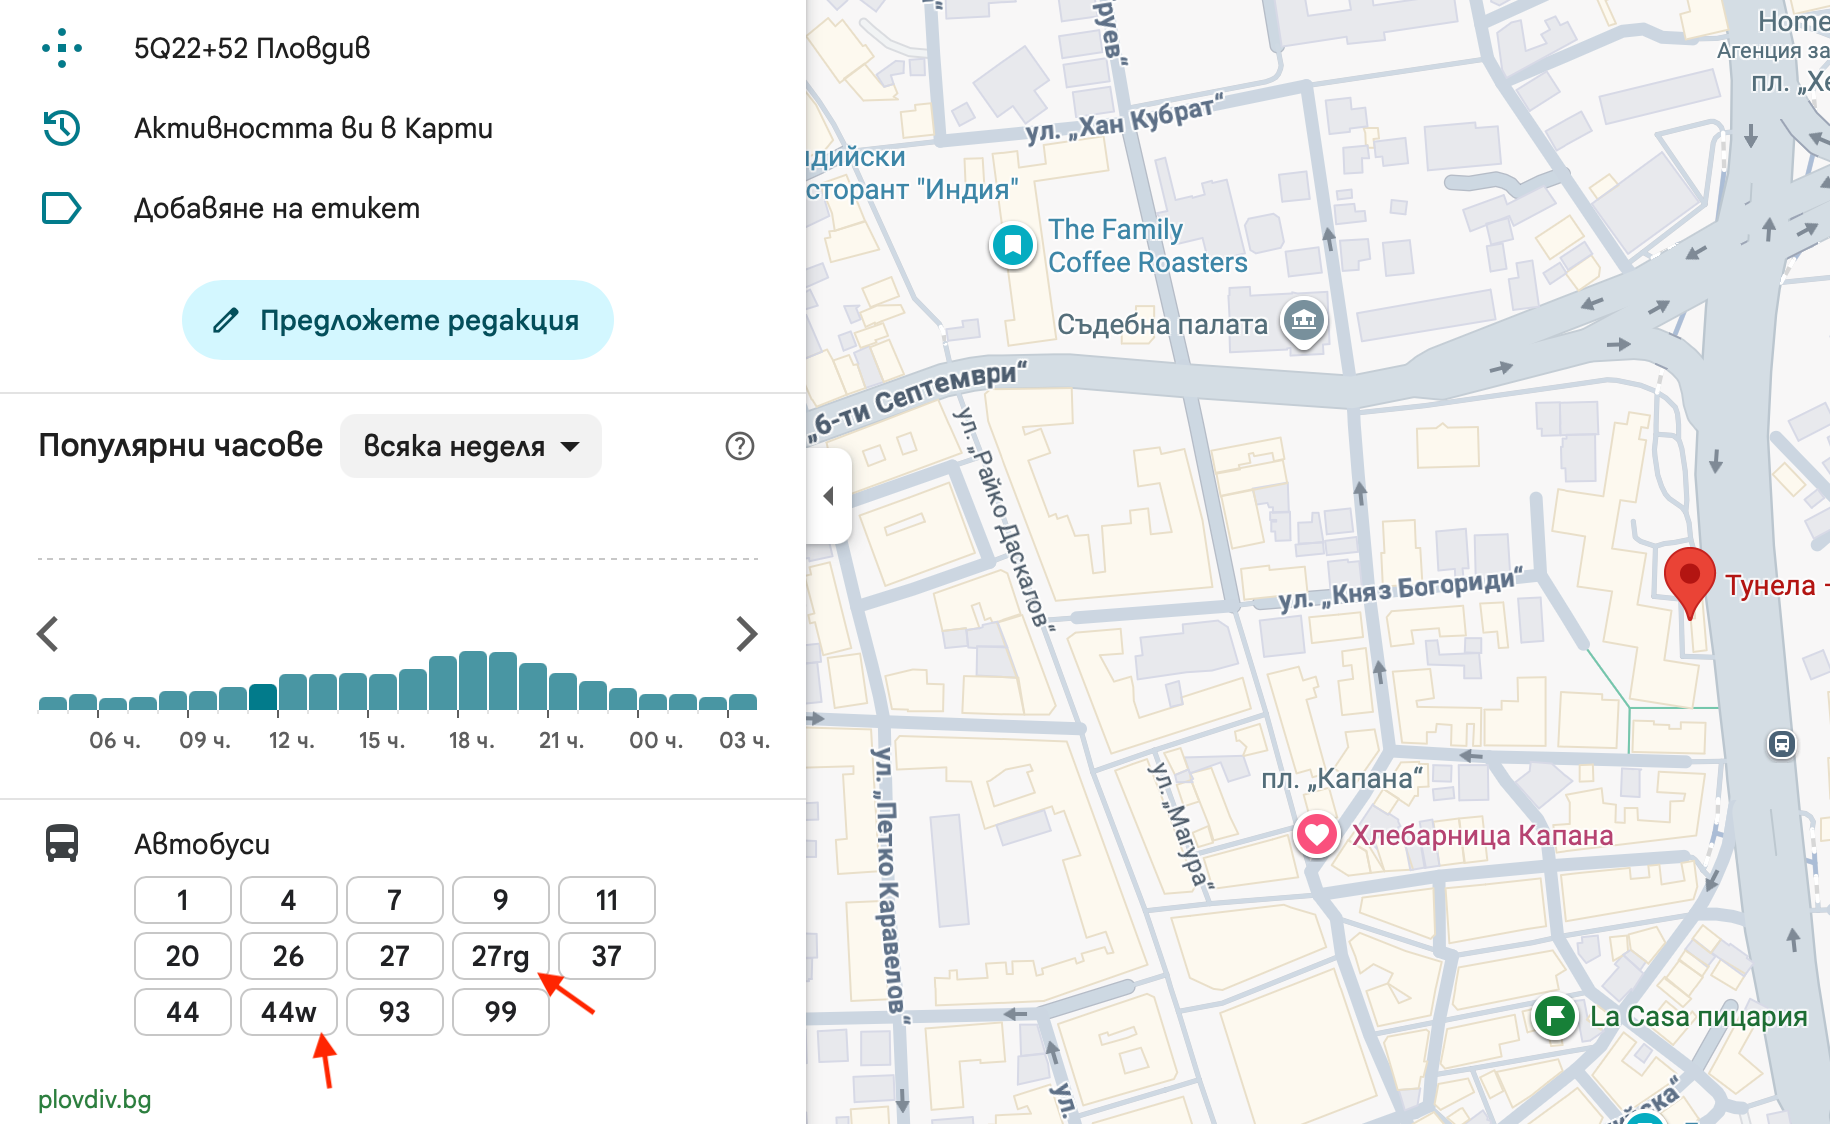
Как знам за това ли? Ами много просто… понеже бяха свършили работата като кучето на нивата, както обичаше да казва баба ми. И понеже не си бяха дали зор да попрегледат изискванията на GTFS, изведнъж (в уж актуализираните данни) се появиха едни странни автобусни линии, които Пловдив няма. Например 44w или 27rg.
Спирка пл. Съединение: Фантомни автобусни линии 44w и 22kСпирка Тунела – север-запад: Фантомни автобусни линии 44w и 27rg
Тези индекси са лично мое дело. Аз съм ги въвел, та си ги познавам. Така разбрах, че са взели нашите данни. Само, че тези индекси не трябва да се виждат, защото не са различни автобусни линии, а модификации на основните. Има няколко линии в града, които в определени дни или часове от деня се движат с модифицирани разписания или маршрути. Затова 44w всъщност е weekend версията на 44, а 27rg са няколкото коли, които вместо до Родина, се движат до Рогошките гробища (rg) и т.н. Схващате идеята. Само, че който се е погрижил за данните през август-септември 2024 не е схванал. И не е прочел достатъчно какво да прави.
Това, че са взели последния комплект от данни, които ние поддържахме не е лошо. Те са публични, а са такива, защото ние държахме да са отворени данни. Лошото е, че са взели един подреден комплект, който само трябваше да актуализират, а всъщност са го оплескали.
Данните с тези грешки и до ден днешен са online и всеки може сам да провери това по-горе. А опасенията ми са, че през 2024 година, в опит бързо да се замаже положението, са качени там някакви си данни и някой от ОКТ или общината е потвърдил пред Google, че те са актуални. Само, че вече сме 2026 година, а през последния месец доста активно използвах градски транспорт, трупайки наблюдения. Това, че разписанията не се спазват е ясно – те и не могат да бъдат спазени, защото не са съобразени с действителността в града. Но има грешки в маршрутите, в началните и крайните времена на тръгване на автобусите и в броя коли, които ги изпълняват. А това Google го разбира, защото „вижда“ движението на телефоните на пътниците по всеки маршрут.
Подозирам и че след извънредния напън през 2024 година да се върнат някакви данни онлайн, след това отново никой не се грижи да ги актуализира. А Google трупа статистика за тези разминавания. И следи дали и кога последно някой е опреснявал данните. Така вероятността Пловдив отново да изпадне от Maps никак не е малка.
През същата 2024 година – т.е. преди малко повече от година – на годишната „Среща на бизнеса от Пловдив, Пазарджик и региона“ бях модератор на панела за дигитализация и транспорт, където от сцената се чуха амбициозни идеи и планове за следващата година. Тя обаче отмина, а нито в посока дигитализация, нито в посока обществен транспорт се забелязва някаква положителна промяна.
Ако има някаква добра новина от последните няколко месеца, тя е, че сякаш поне повече автобуси обслужват линиите на градския транспорт. Но на електронните табла по спирките информацията е все по-оскъдна, до степен да е безполезна. Системата за електронно таксуване е все така доникъде. Някак и нещо работи, но така и нищо не бе официално обявено. Таксуващите устройства (където изобщо ги има) много често не са активни. Шофьорите се правят на три и половина, че не разбират и не е тяхна работа, защото имат интерес да продават хартиени билетчета. И да ги препродават по няколко пъти. А контролът е близко до никакъв.
Автобусите преобладаващо са стари и мръсни. Жегата през лятото е сериозна, а климатиците (когато работят) се пускат колкото за отбиване на номера. Доста от водачите са крайно груби, шофират опасно и пропускат спирки. Разписанията, както вече отбелязах са само пожелателни, а напоследък и трудно откриваеми, освен на сайта на общината, който никой няма желание да гледа.
В този ред на мисли, особено за гости на града, който има претенции да бъде и туристическа дестинация, актуалната информация в Google Maps продължава да бъде повече от пътеводна светлина. Дори с несъвършенствата си.
В края на същата 2024 година бях за седмица на гръцкия остров Корфу. Остров. В Йонийско море. С около 100 хиляди души население. И с безупречен обществен транспорт. Билети и карти могат да се купят от автомати по спирките, плащайки в брой или с карта. Билетите и картите могат да се презареждат с допълнителни пътувания, а интерфейсът на машините може да се превключва на 5-6 езика. В автобусите винаги се качваш от първа врата и валидираш билет или карта при шофьора. Ако нямаш, може да се таксуваш в брой или с банкова карта (но малко по-скъпо) при шофьора. Той е в униформа. И задължително се поздравявате взаимно.
Автобусите са чисти и нови. Всяка предстояща спирка се обявява на дисплей с времето до достигането ѝ. На някои по-нови автобуси се обявяват до три предстоящи спирки. Климатиците работят така, че може да се простудиш.
По спирките има разписания на хартия и QR код, който води до електронната им версия, заедно с информация след колко точно минути идва следващия автобус на точно тази спирка.
В Google Maps сe показват не само маршрутите и разписанията, но и движението на автобусите в реално време (с евентуалните закъснения – дори до минута или две) – нещо, което в Пловдив сигурно ще стане възможно след още едно хилядолетие. Пловдивчани сме айляк, за къде да бързаме толкова…
Ранна зимна сутрин. Софийско училище. Родители изпращат децата си. Водят ги за ръчичка, целуват ги по челата, подават им кутиите с обяда, казват им по нещо, изпращат ги с поглед, докато тежката училищна врата се затваря зад гърбовете им.
И в тези десет минути преди първия час има толкова много нежност и надежда, и любов, че ако човек остане сам със себе си като страничен наблюдател някъде покрай това училище, може и да се залъже, че всичко е наред.
После нещо става. Ръцете се пускат. Кутиите за обяд стават 5 евро за дюнер и енергийна напитка. Никой не се прегръща и целува. Вратата все по-рядко се затваря зад гърбовете на учениците, защото повечето от тях дори не искат да влязат в сградата.
Най-голямото предателство към децата ни е образователната система, в която ги оставихме да се давят. Сцила, Харибда и Янка Такева дебнат отвсякъде. С празнодумните поздравителни адреси за началото на учебната година, застинали в 76-та; с институционалните проверки, симулиращи дейност и никога неразкриващи никакви нарушения; с декларативната важност на документи и стандарти, които ни убеждават, че ще развиваме критично и самостоятелно мислене, а после пак караме децата да дават „правилни“ отговори през наизустени кухи дефиниции.
Тези, които успяват да излязат на сушата, често са осакатени от борбата с морските чудовища. А други така и не доплуват до отсрещния бряг.
През изминалата седмица стана ясно, че едно 18-годишно момче се е самоубило вероятно заради учителски тормоз. Според съучениците му Билгин Алишев от баташкото село Нова махала е сложил край на живота си вследствие на системни обиди и подигравки от преподавателката по английски Елихан Хаджийска.
Момчето е споделяло и е давало сигнали, че е подлагано на тормоз. В деня, в който се самоубива, е бил на „комисия“, разследваща поведението му. Според приятелите му не е имал възможност да се изкаже и не е получил защита от възрастен, с изключение на един от учителите.
Историята на Билгин не е прецедент. Това се случва и в малки населени места, и в столицата, включително в училища с много добра репутация (каквото и да означава това на фона на цялата янкатакевщина). И примиряването с подобна система на образование е най-големият обществен провал на този иначе „много древен, мъдър и изстрадал народ“ (по Ивелин, Костадин, Радостин или друг, завършващ на -ин).
Същият този народ се е запътил бодро към настъпването на поредната мина на 631-вите избори за последните 5 години.
Преди това очаква с нетърпение КОЙ ще бъде служебният премиер. Голямо чакане, голямо нещо. То са разговори, то е чудо. Сърцето ми може и да не издържи на напрежението, докато дебне за новината, че Главчев пак ще е премиер.
Но нека президентката да каже. А дотогава, за да не ви е скучно, вижте защо фактът, че имаме жена президент, не е нещо особено показателно за отношението ни към жените и мястото им в българската политика. В статията си „Имаме си президентка. И?“ Светла Енчева разглежда точно това.
За чакането и гласуването като национален спорт, за турнето на Бойко Борисов по медии и инфлуенсъри и разбира се, за международното положение е новият епизод на „Т.Е. от Е.Т.“, в който освен всичко друго Е.Т. призовава да се купува „Тоест“. С други думи – да се абонирате с месечно дарение, за да може „Тоест“ да продължи да съществува, в случай че имате нужда от това.
Традиционният петъчен политически анализ на Емилия Милчева е посветен на служебния премиер и Изборния кодекс, с които ще разполагаме, за да проведем едни „честни избори“.
Равноотдалечеността е химера. Правителство, чийто премиер се избира измежду политически назначения, били те и високопоставени институционални фигури, няма как да е „неутрално“,
пише Емилия в коментара си „Възелът на съгласието“. Как ще се развие риалити форматът „Избери служебен премиер“, предстои да разберем.
„Стихотворение на месеца“ – „Зимна песен“ от Ана Мария Ленгрен в превод от шведски на Мария Змийчарова.
Една от най-любимите ми поредици в медията – „От дума на дума“, която води Екатерина Петрова, се завръща с нова дума на фокус: „облак“. Защо точно „облак“ и какво толкова интересно има в облаците, ще разберете от текста „Облаче ле бяло“. Препоръчвам ви да не пропускате и бележките под линия, защото те са си достойни за отделен материал.
Още една любима месечна рубрика е в „Тоест“ тази седмица. Новините от света на науката, които Михаил Ангелов подбира и обяснява специално за читателите на медията.
Михаил, който е биолог, агроном и магистър по растителна защита, ще е гост в „Тоест разговаряме“ другата събота (7 февруари) и ще ви скандализира с факта, че в ГМО-то няма нищо лошо. Разговорът ще се излъчи на живо в YouTube Live на 7 февруари, събота, от 16:00 ч.
И в цялата какофония от схеми, избори и преструвки, на 1 февруари „Тоест“ навършва 8 години. Осем години, в които гледаме да не се утешаваме, а да си обясняваме каквото можем. Не се гладим по косъма и не се тупаме по рамото. Не се стараем на всяка цена да е лесно и бързо за четене. „Тоест“ е опит да останем в онези десет минути преди първия час, когато още има смисъл да кажеш нещо важно и навреме. Благодарим ви, че го разбирате. Ако искате да продължим да сме заедно, подкрепете „Тоест“ с месечно дарение.
Scientists have filmed a never-before-seen species of deep-sea squid burying itself upside down in the seafloor—a behavior never documented in cephalopods. They captured the bizarre scene while studying the depths of the Clarion-Clipperton Zone (CCZ), an abyssal plain in the Pacific Ocean targeted for deep-sea mining.
The team described the encounter in a study published Nov. 25 in the journal Ecology, writing that the animal appears to be an undescribed species of whiplash squid. At a depth of roughly 13,450 feet (4,100 meters), the squid had buried almost its entire body in sediment and was hanging upside down, with its siphon and two long tentacles held rigid above the seafloor.
“The fact that this is a squid and it’s covering itself in mud—it’s novel for squid and the fact that it is upside down,” lead author Alejandra Mejía-Saenz, a deep-sea ecologist at the Scottish Association for Marine Science, told Live Science. “We had never seen anything like that in any cephalopods…. It was very novel and very puzzling.”
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
This week brings 3 new pieces of module content for targeting FreePBX. All three chain multiple vulnerabilities together, starting with CVE-2025-66039. This initial vulnerability allows unauthenticated users to bypass the authentication process to interact with FreePBX. From this point, the different modules leverage either a SQL injection vulnerability (CVE-2025-61675) or a file upload vulnerability (CVE-2025-61678) to obtain remote code execution.
New module content (7)
FreePBX endpoint SQLi to RCE
Authors: Noah King and msutovsky-r7 Type: Exploit Pull request: #20857 contributed by msutovsky-r7 Path: unix/http/freepbx_custom_extension_rce AttackerKB reference: CVE-2025-61675
Description: This adds exploit module for FreePBX which chains an authentication bypass, CVE-2025-66039, with a SQLi, CVE-2025-61675, which allows for a cron job to be added to the cron_job table of the database to allow for Remote Code Execution.
FreePBX firmware file upload
Authors: Noah King and msutovsky-r7 Type: Exploit Pull request: #20858 contributed by msutovsky-r7 Path: unix/http/freepbx_firmware_file_upload AttackerKB reference: CVE-2025-61678
Description: This adds exploit module for FreePBX which chains an authentication bypass, CVE-2025-66039, with an unrestricted file upload (via firmware upload), CVE-2025-61678, which allows for a webshell to be uploaded to the webserver resulting in remote code execution.
FreePBX Custom Extension SQL Injection
Authors: Noah King and msutovsky-r7 Type: Auxiliary Pull request: #20846 contributed by msutovsky-r7 Path: gather/freepbx_custom_extension_injection AttackerKB reference: CVE-2025-61675
Description: This adds an exploit module for FreePBX which chains an authentication bypass, (CVE-2025-66039) with an SQLi (CVE-2025-61675) to create an admin user in the database.
Cacti Graph Template authenticated RCE versions prior to 1.2.29
Authors: Jack Heysel and chutchut Type: Exploit Pull request: #20799 contributed by jheysel-r7 Path: multi/http/cacti_graph_template_rce AttackerKB reference: CVE-2025-24367
Description: This adds an exploit for CVE-2025-24367 which is an unauthenticated RCE in Cacti.
Authors: Piotr Bazydlo, Sina Kheirkhah, and jheysel-r7 Type: Exploit Pull request: #20866 contributed by jheysel-r7 Path: multi/http/smartermail_guid_file_upload AttackerKB reference: CVE-2025-52691
Description: This adds a module for unauthenticated file upload in SmarterTools SmaterMail (CVE-2025-52691). The vulnerability allows an unauthenticated user to upload a file to any location on the system using path traversal using the guid variable. The module will either drop a webshell in the webroot directory (if the target is Windows) or create a cron job by dropping a file in /etc/cron.d (if the target is Linux).
Description: This adds a new persistence module for BurpSuite. The module adds a malicious extension to both the Pro and Community versions, which is triggered when the user starts BurpSuite.
Description: Combines the Windows and Linux ssh key persistence modules.
Enhancements and features (1)
#20778 from h00die – Combines the Windows and Linux ssh key persistence modules.
Bugs fixed (3)
#20897 from h00die – This fixes a bug that was preventing collected hash data from being formatted as input for the John the Ripper cracker. The result is that users can now once again crack passwords using John.
#20902 from rudraditya21 – This fixes a bug in the auxiliary/scanner/ssh/ssh_login module that would incorrectly state that a login failed when it in fact succeeded but the module was unable to open a session. This was only an issue when the CreateSession option is true.
#20909 from adfoster-r7 – Fixes a bug in Metasploit Pro that reported false positives for HTTP bruteforcing.
Documentation
You can find the latest Metasploit documentation on our docsite at docs.metasploit.com.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate and you can get more details on the changes since the last blog post from GitHub:
You can use AWS Directory Service for Microsoft Active Directory as your primary Active Directory Forest for hosting your users’ identities. Your IT teams can continue using existing skills and applications while your organization benefits from the enhanced security, reliability, and scalability of AWS managed services. You can also run AWS Managed Microsoft AD as a resource forest. In this configuration, AWS Managed Microsoft AD serves supported AWS services while users’ identities remain under exclusive control of your organization on a self-managed Active Directory. As your organization grows and scales, so will your AWS Managed Microsoft AD deployments.
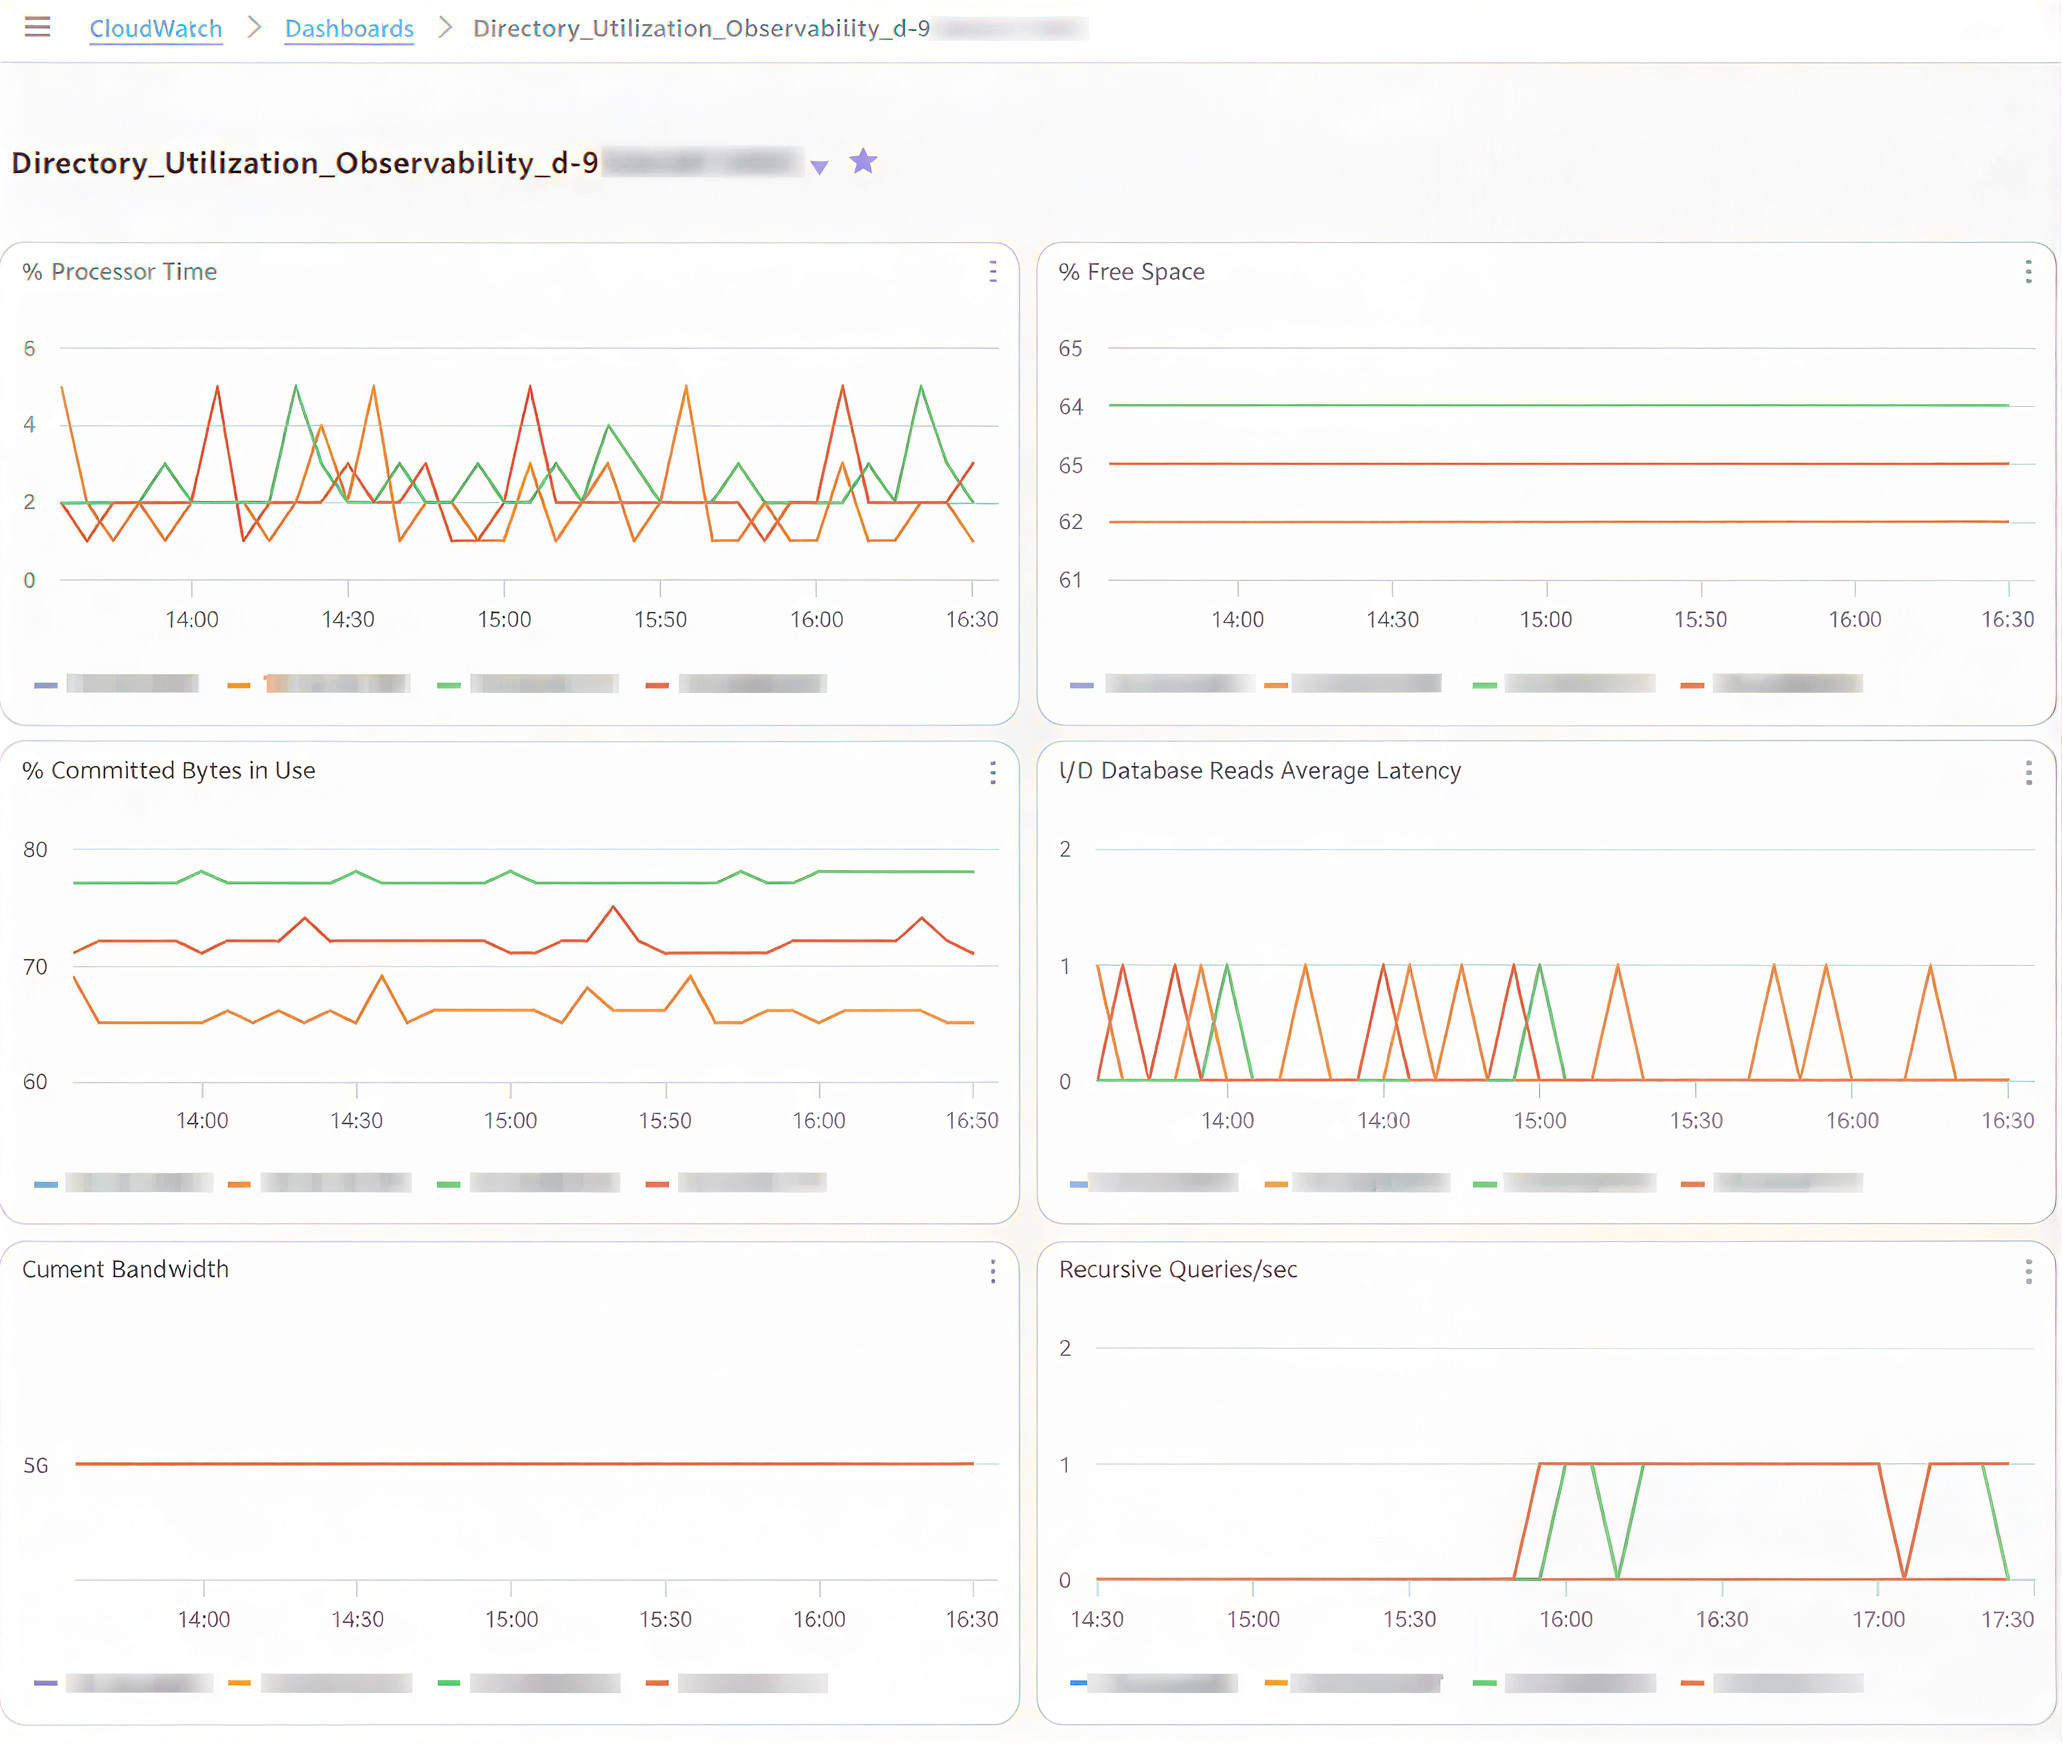
In this post, you’ll learn how to use Amazon CloudWatch dashboards to monitor key performance metrics of your AWS Managed Microsoft AD deployment to track and analyze a directory’s performance over time. You can then use that information to determine when and how best to scale directory services for optimal performance.
Scaling your Active Directory
When you deploy AWS Managed Microsoft AD, the service initially creates two domain controller instances in two separate subnets of the same virtual private cloud (VPC). This architecture economically provides resiliency and high availability with a minimal set of resources. This initial configuration enables every feature that AWS Managed Microsoft AD offers. As your organization grows, its workflows will become larger and more complex, requiring that you scale your directories accordingly. AWS Managed Microsoft AD simplifies and makes the scaling process secure with minimal administrative effort. When it’s time to scale a directory, AWS Managed Microsoft AD offers two options: scale-up or scale-out.
Understanding scale-up and scale-out
Scale-up—also called upgrading your AWS Managed Microsoft AD—means changing the edition of an AWS Managed Microsoft AD from Standard to Enterprise. Enterprise Edition delivers larger domain controller instances, with higher compute capacity and larger storage for Active Directory objects. When a directory scales up, it retains the same number of domain controller instances that it previously had with larger quotas. Instances are replaced one at a time to minimize disruptions to production workflows.
A few features offered by the service are a better fit for the size and compute power of Enterprise Edition AWS Managed Microsoft AD and so are only available in Enterprise Edition. Consider scaling-up your directory if you encounter any of the following scenarios:
You plan to replicate your directory across multiple AWS Regions. Multi-Region replication is only available in Enterprise Edition.
The number of Active Directory objects in the directory will exceed the recommended threshold of 30,000 objects for Standard Edition. Enterprise Edition can accommodate up to 500,000 directory objects.
You plan to share your directory with more than 25 other AWS accounts. The default directory sharing quota is 25 accounts for Standard Edition and 500 for Enterprise Edition.
Important: Scaling up a directory from Standard to Enterprise is a one-way operation that cannot be reverted and operates at a higher hourly price.
Scale-out means deploying additional domain controllers for your AWS Managed Microsoft AD. You can scale out both Standard or Enterprise directories and can scale out different Regions independently. You don’t need to scale every Region to the same number of domain controller instances. When scale-out takes place, additional domain controller instances with the same compute resources and storage capacity as existing ones are launched in the same subnets.
Because some operations cannot be reverted, it’s important to understand the impact of each scaling operation. It’s preferable to scale out the number of domain controllers first, because you can revert that change if necessary. Consider scaling up first only if you need a feature that’s only available in Enterprise Edition.
Making an informed decision using CloudWatch
Since December 2021, AWS Managed Microsoft AD helps optimize scaling decisions with directory metrics in Amazon CloudWatch. Amazon CloudWatch metrics are a time-ordered set of data-points about performance indicators of a system that you can use to monitor and analyze performance over time. Metrics are stored as a time-series set and each data point has an associated timestamp. By using CloudWatch, you can create alarms based on metrics and visualize and analyze metrics to derive new insights.
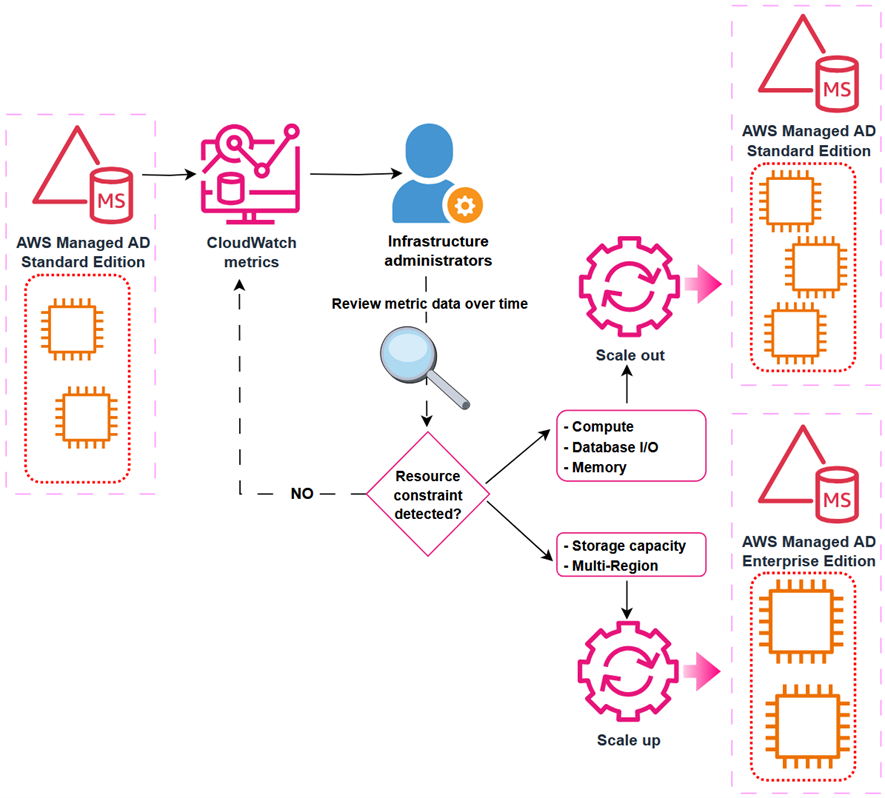
To understand the performance of a directory over time, define the key performance metrics based on your workload when you create the directory. Record the initial values of those metrics to create a performance baseline. Periodically revisit and compare data points for the same metrics to understand trends and use of resources over time. Based on the information provided by the performance baseline and periodic follow-ups, you can decide when to scale your directory and what scaling method to use. This process is depicted in Figure 1.
Figure 1: Decision-making process for scaling an Active Directory implementation
Depending on the characteristics of your workload, you might face different resource constraints in your directory system. From an infrastructure perspective, the more commonly demanded resources are:
Network Interface: Current Bandwidth
Processor: % Processor Time
LogicalDisk: % Free Space
From an Active Directory perspective, consider metrics such as:
NTDS: LDAP Searches/sec
NTDS: ATQ Estimated Queue Delay
The following table is an example decision matrix based on which resource is constrained.
Constrained resource
Recommended action
% Processor Time
Scale out
I/O Database Reads Average Latency
Scale out
Committed Bytes in Use
Scale out
% Free Space
Scale up
For example, you can create a CloudWatch alarm that will trigger when Processor: % Processor Time is over 80% for more than 5 minutes. If this alarm triggers often, it could be a signal that domain controller instances are struggling to service the regular volume of user authentication requests. In such a scenario, you might consider scaling-out an additional domain controller to guarantee the service’s SLA. Conversely, if the LogicalDisk: % Free Space drops below 10% and trends downwards, you might consider scaling-up to Enterprise Edition, because it provides a larger capacity for directory objects.
To facilitate tracking and analyzing performance of AWS Managed Microsoft AD over time, you can use Amazon CloudWatch to create a custom dashboard including relevant metrics.
Prerequisites
Before you get started, make sure that you have the following prerequisites in place:
In the navigation pane, choose Dashboards, and then choose Create dashboard.
In the Create new dashboard dialog box, enter a name for the dashboard and then choose Create dashboard.
When the Add widget window appears:
Under Data sources types, select CloudWatch.
Under Data type, select Metrics.
Under Widget type, select Line.
Choose Next.
In the Add metric graph window, choose DirectoryService and then select Processor as the Metric category and % Processor Time under Metric name. Select each instance of the metric, represented as theDomain Controller IP, for one Directory ID.
Choose Create widget.
Note: if there are multiple directories in the same Region, all instances (domain controllers IPs) will be available for selection. To help ensure effective monitoring and alarms, create a separate dashboard for each directory.
Choose the plus sign (+) at the top of the window to add more widgets. Repeat steps 1–6 to add additional widgets for other relevant metrics. In this example the metric categories and names added are:
The following are recommended thresholds to monitor when determining the need to scale an AWS Managed Microsoft AD. These are general recommendations based on standard use cases. You might have to adjust these thresholds to make the best scaling decisions for your organization.
Processor: % Processor Time: Monitor CPU utilization to understand computational demands on your domain controllers. Set CloudWatch alarms at 80% for a period of 5 minutes. Sustained high values indicate potential sizing issues that might require scaling out your directory.
LogicalDisk: % Free Space: Maintain at least 25% free space on volumes containing Active Directory data for optimal performance. Set CloudWatch alarms to trigger when free space drops below 20%. Low disk space can severely impact directory operations and require implementing cleanup procedures or scaling up the directory.
Network Interface: Current Bandwidth: Average network utilization should be kept below 50% of available bandwidth during peak operations for optimal directory responsiveness. Set CloudWatch alarms at 70% utilization to allow room for spikes in activity. Consistently high values suggest network constraints that might require scaling out your directory.
Memory: Committed Bytes in Use: Monitor memory commitment levels to help ensure that your domain controllers have sufficient memory resources for Active Directory operations. This metric tracks the amount of virtual memory that has been committed, indicating the total memory load on your domain controllers. Set CloudWatch alarms at 80% of the commit limit. Sustained high values can lead to excessive paging, significantly degrading directory performance and potentially causing authentication delays.
Database: I/O Database Reads Average Latency: Maintain average read latencies below 25 milliseconds. Set CloudWatch alarms at a threshold of 50 milliseconds. If read latencies are consistently elevated, consider scaling-out your directory.
DNS: Recursive Queries/sec: Given the tight integration of Active Directory with DNS, monitor this metric for stability and predictable patterns. Use CloudWatch anomaly detection rather than fixed thresholds to identify unexpected behaviors that could indicate DNS configuration issues or potential security concerns.
Post-scaling considerations
Different resources across your architecture might contain references to the IP addresses of the AWS Managed Microsoft AD. After a scale-out operation that deploys additional domain controller instances on a directory, update existing references to maintain full functionality of workloads. References for the directory’s IP addresses can be found (but might not be limited to) the following services:
To maintain the full functionality of your workloads after a directory scaling operation, update the following:
Firewall rules that allow traffic to and from the IP addresses of domain controller instances
Route53 Resolver endpoint rules and DNS conditional forwarders that forward queries to the directory instances
CloudWatch dashboards that display metric data about the directory to include dimensions for the new IP addresses
Clean up resources
In this post, you created components that generate costs. Clean up these resources when no longer required to avoid additional charges.
Remove added domain controller’s IP addresses from firewall rules, resolver endpoint rules and DNS conditional forwarders.
Delete the custom CloudWatch dashboards you don’t plan to keep.
Scale back existing directories to the previous number of domain controller instances.
Conclusion
In this post, you learned how to monitor directory performance metrics using Amazon CloudWatch. By combining performance baselines, monitoring, and planning, you can make informed decisions about when and how to scale a directory safely and efficiently. By scaling directories in a timely manner, you can optimize efficiency and reduce the risk of outages by having a right-sized directory service to support your organization’s workloads.
Scale out your directory when your Active Directory-aware workflows have grown over time and the solution requires additional domain controller instances to maintain the service SLA. Scale up your directory when you require a feature that’s only available in Enterprise Edition AWS Managed Microsoft AD, such as multi-Region replication or additional storage to accommodate Active Directory objects. By using the flexible scaling capabilities and independent Regional expansion, you can optimize costs while maintaining appropriate service levels.
To learn more about AWS Managed Microsoft AD optimization and monitoring with Amazon CloudWatch, see:
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.