As we close out 2025, one thing is clear: the security landscape is evolving faster than most organizations can keep up. From surging ransomware campaigns and AI-enhanced phishing to data extortion, geopolitical fallout, and gaps in cyber readiness, the challenges facing security teams today are as varied as they are relentless. But with complexity comes clarity and insight.
This year’s most significant breaches, breakthroughs, and behavioral shifts provide a critical lens through which we can view what’s next. That’s exactly what we’ll explore in our upcoming Security Predictions for 2026 webinar, where Rapid7’s experts will break down where we are now, what to expect next, and how organizations can proactively adapt.
Before we look ahead, let’s take stock of what defined 2025 and what it tells us about the state of cybersecurity today.
Ransomware: Same playbook, more precision
Ransomware remains one of the most consistent and costly threats facing organisations today, but the approach has shifted. According to Rapid7’s Q3 2025 Threat Landscape Report, data extortion continues to dominate, with groups increasingly focused on exfiltration and disruption rather than encryption alone. Over 80% of ransomware cases handled in Q3 involved data theft, often staged and timed to maximise leverage.
Threat actors like RansomHub, BlackSuit, NoEscape, and Scattered Spider continue to refine their operations. Many campaigns are multi-stage and collaborative, with Initial Access Brokers providing footholds that are later sold to ransomware operators. One common thread is a focus on identity and infrastructure abuse – attackers are compromising vSphere environments, exploiting misconfigurations in third-party platforms, and abusing legitimate remote access tools to move laterally before launching extortion phases.
These incidents increasingly target complex organizations with sprawling digital footprints. The result? Weeks of operational downtime, lost revenue, regulatory scrutiny, and enduring brand damage. In this landscape, ransomware is no longer just a malware problem – it’s a business continuity issue, a supply chain risk, and a board-level concern.
The offense is automated: AI goes to work
This year, we saw AI break through hype and land firmly in attackers’ toolkits. Tools like WormGPT, FraudGPT, and DarkBERT gave cybercriminals an entry point to generate convincing phishing emails, polymorphic malware, and credential-harvesting scripts, all without needing advanced coding skills.
In our AI Offense blog, we detailed how these tools lower the barrier to entry and amplify the volume and sophistication of social engineering campaigns. Pair that with deepfakes, cloned voices, and LLM-powered targeting, and security teams now face threats that are faster, cheaper, and harder to detect than ever before.
The takeaway? AI is not a future threat. It is here. And defenders must embrace its potential just as aggressively as attackers have.
The human factor: Still the weakest link
Despite improved tooling, attacker playbooks still rely heavily on people. Our recent exploration of evolving social engineering trends highlighted the rise of Microsoft Teams-based impersonation, remote access tool abuse such as Quick Assist, and multi-stage credential compromise.
The fallout has been widespread. From attacks on major UK retailers to multiple airline disruptions and critical public sector breaches, social engineering is no longer just email phishing. It is phone calls, voice cloning, fake calendars, and chat-based manipulation.
Training helps. But attackers are innovating faster than awareness campaigns can keep up. Security teams need to simulate these threats internally and invest in visibility across identity platforms, because credentials remain the crown jewels.
From awareness to action: Resilience as a mandate
A growing number of incidents in 2025 underscored the readiness gap in many organizations. Our recent blog on preparedness broke down the UK’s National Cyber Security Centre guidance urging companies to revisit their offline contingency planning, including printed IR protocols and analog communications in case digital systems are taken offline.
This call followed a sharp rise in high-impact events, with over 200 nationally significant cyber incidents recorded in the UK alone this year.
The lesson? Cyber resilience is not a nice to have. It is foundational. Detection, backup, and patching are essential, but so is building response plans that assume failure, simulate outages, and bring the entire business to the table.
Join us: Predicting what’s next in 2026
We’ll explore these trends and where they’re heading in much greater depth in our Security Predictions for 2026 webinar, taking place on December 10.
Rapid7’s experts will unpack:
Which attacker tactics are here to stay and which are on the rise
Where AI, regulation, and infrastructure gaps are creating new exposures
How defenders can better prioritise risk and operate in resource-constrained environments
What CISOs, SOC leaders, and engineers need to align on in 2026 to stay ahead
This is our biggest global webinar of the year, and it is designed to help security professionals at every level get proactive and stay ahead of what’s next.
Register now and join thousands of security professionals from around the world as we set the stage for 2026. Because when the threat landscape keeps shifting, your best defense is a head start.
There have been several recent announcements about Linux distributions changing
the list of architectures they support, or adjusting how they build binaries for
some versions of those architectures.
Ubuntu introduced architecture variants, Fedora considered dropping support for i686 but
reversed course after some pushback, and Debian developers
have discussed raising its architecture baseline for the upcoming
Debian 14
(“forky”).
Linux supports a large number of architectures, and it’s not always
clear where or by whom they are used.
With increasing concerns about diminishing support for legacy
architectures, it’s a good time to look at the overall state of architecture
support on Linux.
The Homebrew project is an
open-source package-management system that comes with a repository of
useful packages for Linux and macOS. Even though Linux distributions
have their own package management and repositories, Homebrew is often
used to obtain software that is not available in a distribution’s repository
or to install more current versions of projects than are available
from long-term-support (LTS) distributions. Homebrew 5.0.0,
released on November 12, 2025, expanded Linux support to include
64-bit Arm packages in addition to x86_64, and turned on concurrent
downloads by default to speed up package downloads.
In most organizations, printing is an essential but often invisible service. When it works, nobody notices. When it fails, productivity stalls. That’s why monitoring your print environment is just as important as monitoring servers, databases, or network devices.
At Opensource ICT Solutions, we specialize in turning complex systems into observable services. One recent example is our integration of PaperCut NG with Zabbix. This allows IT teams to track the health of their print infrastructure in real-time — everything from server resources to individual printers and devices.
Why monitoring PaperCut matters
PaperCut NG does much more than queue print jobs. It enforces quotas, integrates with authentication systems, and manages fleets of devices. If the database runs out of connections, the disk fills up, or the license expires, users feel the impact instantly.
By integrating PaperCut with Zabbix, we make these risks visible long before they become business problems. The result is:
Proactive detection of printer errors, low toner, or license issues.
Capacity planning through trend analysis of disk usage, memory, and DB connections.
Unified visibility — PaperCut health checks appear right alongside servers, networks, and applications in Zabbix dashboards.
How the integration works
The magic happens through the PaperCut System Health API and Zabbix’s flexible data collection methods.
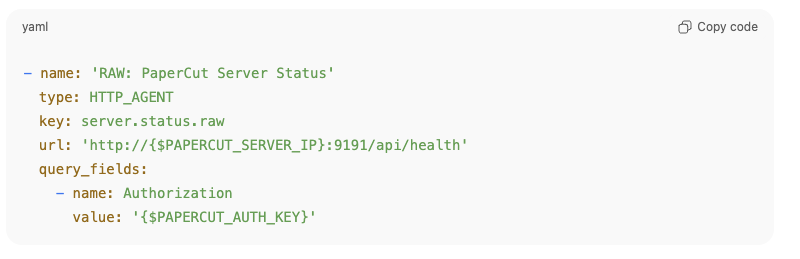
HTTP agent items
Zabbix fetches raw JSON data directly from PaperCut using an HTTP agent item, such as:
This single call provides a full snapshot of server health.
Dependent items + JSONPATH
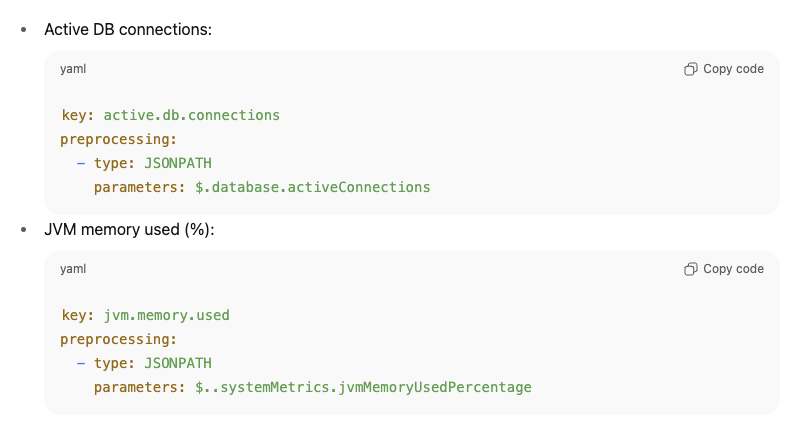
Instead of hammering the API with multiple requests, we extract the needed fields using dependent items with JSONPATH preprocessing.
For example:
This design means one request can populate dozens of metrics, keeping monitoring both efficient and lightweight.
Calculated items
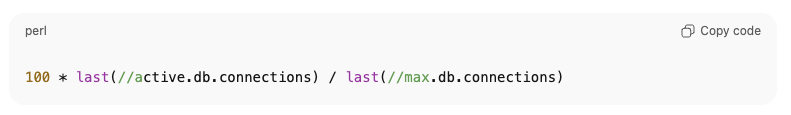
Some values aren’t directly available from PaperCut. In those cases, we create calculated items inside Zabbix.
For example, the percentage of active DB connections is derived as:
This allows us to set intelligent triggers like “DB connections > 90%” without requiring PaperCut to calculate it for us.
Low-level discovery (LLD) for devices and printers
Perhaps the most powerful part of this integration is automatic discovery.
Printer LLD → Queries /api/health/printers and creates items and triggers per printer. If a printer goes into Paper Jam or No Toner, Zabbix knows immediately.
Device LLD → Queries /api/health/devices and builds items dynamically for each discovered device, tracking states like OK, WARNING, or ERROR.
This ensures that new printers and devices are monitored automatically — no manual configuration required!
Why this matters
Bringing all of this together, the integration turns PaperCut NG into a fully observable service inside Zabbix.
Efficiency → One API call, dozens of metrics.
Scalability → Automatic discovery of printers and devices.
Robustness → Alerts and dashboards for licenses, resources, and print queues.
For IT teams, this means fewer surprises, faster troubleshooting, and more confidence in a service that often goes unnoticed until it fails.
Our expertise
This PaperCut integration is just one example of how we at Opensource ICT Solutions help organizations unlock the full potential of Zabbix. We don’t just install monitoring – we design intelligent, scalable integrations that make hidden systems visible. Whether it’s print management, databases, custom applications, or network devices, we know how to extend Zabbix to fit your environment and give you the insights that matter most.
Security updates have been issued by Debian (libwebsockets), Fedora (chromium and fvwm3), Mageia (apache, firefox, and postgresql13, postgresql15), Oracle (idm:DL1), Red Hat (bind, bind9.18, firefox, and openssl), SUSE (alloy, ghostscript, and openssl-1_0_0), and Ubuntu (ffmpeg and freeglut).
Social media has been a familiar, even mundane, part of life for nearly two decades. It can be easy to forget it was not always that way.
In 2008, social media was just emerging into the mainstream. Facebook reached 100 million users that summer. And a singular candidate was integrating social media into his political campaign: Barack Obama. His campaign’s use of social media was so bracingly innovative, so impactful, that it was viewed by journalist David Talbot and others as the strategy that enabled the first term Senator to win the White House.
Over the past few years, a new technology has become mainstream: AI. But still, no candidate has unlocked AI’s potential to revolutionize political campaigns. Americans have three more years to wait before casting their ballots in another Presidential election, but we can look at the 2026 midterms and examples from around the globe for signs of how that breakthrough might occur.
How Obama Did It
Rereading the contemporaneous reflections of the New York Times’ late media critic, David Carr, on Obama’s campaign reminds us of just how new social media felt in 2008. Carr positions it within a now-familiar lineage of revolutionary communications technologies from newspapers to radio to television to the internet.
The Obama campaign and administration demonstrated that social media was different from those earlier communications technologies, including the pre-social internet. Yes, increasing numbers of voters were getting their news from the internet, and content about the then-Senator sometimes made a splash by going viral. But those were still broadcast communications: one voice reaching many. Obama found ways to connect voters to each other.
In describing what social media revolutionized in campaigning, Carr quotes campaign vendor Blue State Digital’s Thomas Gensemer: “People will continue to expect a conversation, a two-way relationship that is a give and take.”
The Obama team made some earnest efforts to realize this vision. His transition team launched change.gov, the website where the campaign collected a “Citizen’s Briefing Book” of public comment. Later, his administration built We the People, an online petitioning platform.
But the lasting legacy of Obama’s 2008 campaign, as political scientists Hahrie Han and Elizabeth McKenna chronicled, was pioneering online “relational organizing.” This technique enlisted individuals as organizers to activate their friends in a self-perpetuating web of relationships.
Perhaps because of the Obama campaign’s close association with the method, relational organizing has been touted repeatedly as the linchpin of Democratic campaigns: in 2020, 2024, and today. But research by non-partisan groups like Turnout Nation and right-aligned groups like the Center for Campaign Innovation has also empirically validated the effectiveness of the technique for inspiring voter turnout within connected groups.
The Facebook of 2008 worked well for relational organizing. It gave users tools to connect and promote ideas to the people they know: college classmates, neighbors, friends from work or church. But the nature of social networking has changed since then.
For the past decade, according to Pew Research, Facebook use has stalled and lagged behind YouTube, while Reddit and TikTok have surged. These platforms are less useful for relational organizing, at least in the traditional sense. YouTube is organized more like broadcast television, where content creators produce content disseminated on their own channels in a largely one-way communication to their fans. Reddit gathers users worldwide in forums (subreddits) organized primarily on topical interest. The endless feed of TikTok’s “For You” page disseminates engaging content with little ideological or social commonality. None of these platforms shares the essential feature of Facebook c. 2008: an organizational structure that emphasizes direct connection to people that users have direct social influence over.
AI and Relational Organizing
Ideas and messages might spread virally through modern social channels, but they are not where you convince your friends to show up at a campaign rally. Today’s platforms are spaces for political hobbyism, where you express your political feelings and see others express theirs.
Relational organizing works when one person’s action inspires others to do this same. That’s inherently a chain of human-to-human connection. If my AI assistant inspires your AI assistant, no human notices and one’s vote changes. But key steps in the human chain can be assisted by AI. Tell your phone’s AI assistant to craft a personal message to one friend—or a hundred—and it can do it.
So if a campaign hits you at the right time with the right message, they might persuade you to task your AI assistant to ask your friends to donate or volunteer. The result can be something more than a form letter; it could be automatically drafted based on the entirety of your email or text correspondence with that friend. It could include references to your discussions of recent events, or past campaigns, or shared personal experiences. It could sound as authentic as if you’d written it from the heart, but scaled to everyone in your address book.
Research suggests that AI can generate and perform written political messaging about as well as humans. AI will surely play a tactical role in the 2026 midterm campaigns, and some candidates may even use it for relational organizing in this way.
(Artificial) Identity Politics
For AI to be truly transformative of politics, it must change the way campaigns work. And we are starting to see that in the US.
The earliest uses of AI in American political campaigns are, to be polite, uninspiring. Candidates viewed them as just another tool to optimize an endless stream of email and text message appeals, to ramp up political vitriol, to harvest data on voters and donors, or merely as a stunt.
Of course, we have seen the rampant production and spread of AI-powered deepfakes and misinformation. This is already impacting the key 2026 Senate races, which are likely to attract hundreds of millions of dollars in financing. Roy Cooper, Democratic candidate for US Senate from North Carolina, and Abdul El-Sayed, Democratic candidate for Senate from Michigan, were both targeted by viral deepfake attacks in recent months. This may reflect a growing trend in Donald Trump’s Republican party in the use of AI-generated imagery to build up GOP candidates and assail the opposition.
And yet, in the global elections of 2024, AI was used more memetically than deceptively. So far, conservative and far right parties seem to have adopted this most aggressively. The ongoing rise of Germany’s far-right populist AfD party has been credited to its use of AI to generate nostalgic and evocative (and, to many, offensive) campaign images, videos, and music and, seemingly as a result, they have dominated TikTok. Because most social platforms’ algorithms are tuned to reward media that generates an emotional response, this counts as a double use of AI: to generate content and to manipulate its distribution.
AI can also be used to generate politically useful, though artificial, identities. These identities can fulfill different roles than humans in campaigning and governance because they have differentiated traits. They can’t be imprisoned for speaking out against the state, can be positioned (legitimately or not) as unsusceptible to bribery, and can be forced to show up when humans will not.
In Venezuela, journalists have turned to AI avatars—artificial newsreaders—to report anonymously on issues that would otherwise elicit government retaliation. Albania recently “appointed” an AI to a ministerial post responsible for procurement, claiming that it would be less vulnerable to bribery than a human. In Virginia, both in 2024 and again this year, candidates have used AI avatars as artificial stand-ins for opponents that refused to debate them.
And yet, none of these examples, whether positive or negative, pursue the promise of the Obama campaign: to make voter engagement a “two-way conversation” on a massive scale.
The closest so far to fulfilling that vision anywhere in the world may be Japan’s new political party, Team Mirai. It started in 2024, when an independent Tokyo gubernatorial candidate, Anno Takahiro, used an AI avatar on YouTube to respond to 8,600 constituent questions over a seventeen-day continuous livestream. He collated hundreds of comments on his campaign manifesto into a revised policy platform. While he didn’t win his race, he shot up to a fifth place finish among a record 56 candidates.
Anno was RECENTLY elected to the upper house of the federal legislature as the founder of a new party with a 100 day plan to bring his vision of a “public listening AI” to the whole country. In the early stages of that plan, they’ve invested their share of Japan’s 32 billion yen in party grants—public subsidies for political parties—to hire engineers building digital civic infrastructure for Japan. They’ve already created platforms to provide transparency for party expenditures, and to use AI to make legislation in the Diet easy, and are meeting with engineers from US-based Jigsaw Labs (a Google company) to learn from international examples of how AI can be used to power participatory democracy.
Team Mirai has yet to prove that it can get a second member elected to the Japanese Diet, let alone to win substantial power, but they’re innovating and demonstrating new ways of using AI to give people a way to participate in politics that we believe is likely to spread.
Organizing with AI
AI could be used in the US in similar ways. Following American federalism’s longstanding model of “laboratories of democracy,” we expect the most aggressive campaign innovation to happen at the state and local level.
D.C. Mayor Muriel Bowser is partnering with MIT and Stanford labs to use the AI-based tool deliberation.io to capture wide scale public feedback in city policymaking about AI. Her administration said that using AI in this process allows “the District to better solicit public input to ensure a broad range of perspectives, identify common ground, and cultivate solutions that align with the public interest.”
It remains to be seen how central this will become to Bowser’s expected re-election campaign in 2026, but the technology has legitimate potential to be a prominent part of a broader program to rebuild trust in government. This is a trail blazed by Taiwan a decade ago. The vTaiwan initiative showed how digital tools like Pol.is, which uses machine learning to make sense of real time constituent feedback, can scale participation in democratic processes and radically improve trust in government. Similar AI listening processes have been used in Kentucky, France, and Germany.
Even if campaigns like Bowser’s don’t adopt this kind of AI-facilitated listening and dialog, expect it to be an increasingly prominent part of American public debate. Through a partnership with Jigsaw, Scott Rasmussen’s Napolitan Institute will use AI to elicit and synthesize the views of at least five Americans from every Congressional district in a project called “We the People.” Timed to coincide with the country’s 250th anniversary in 2026, expect the results to be promoted during the heat of the midterm campaign and to stoke interest in this kind of AI-assisted political sensemaking.
In the year where we celebrate the American republic’s semiquincentennial and continue a decade-long debate about whether or not Donald Trump and the Republican party remade in his image is fighting for the interests of the working class, representation will be on the ballot in 2026. Midterm election candidates will look for any way they can get an edge. For all the risks it poses to democracy, AI presents a real opportunity, too, for politicians to engage voters en masse while factoring their input into their platform and message. Technology isn’t going to turn an uninspiring candidate into Barack Obama, but it gives any aspirant to office the capability to try to realize the promise that swept him into office.
This essay was written with Nathan E. Sanders, and originally appeared in The Fulcrum.
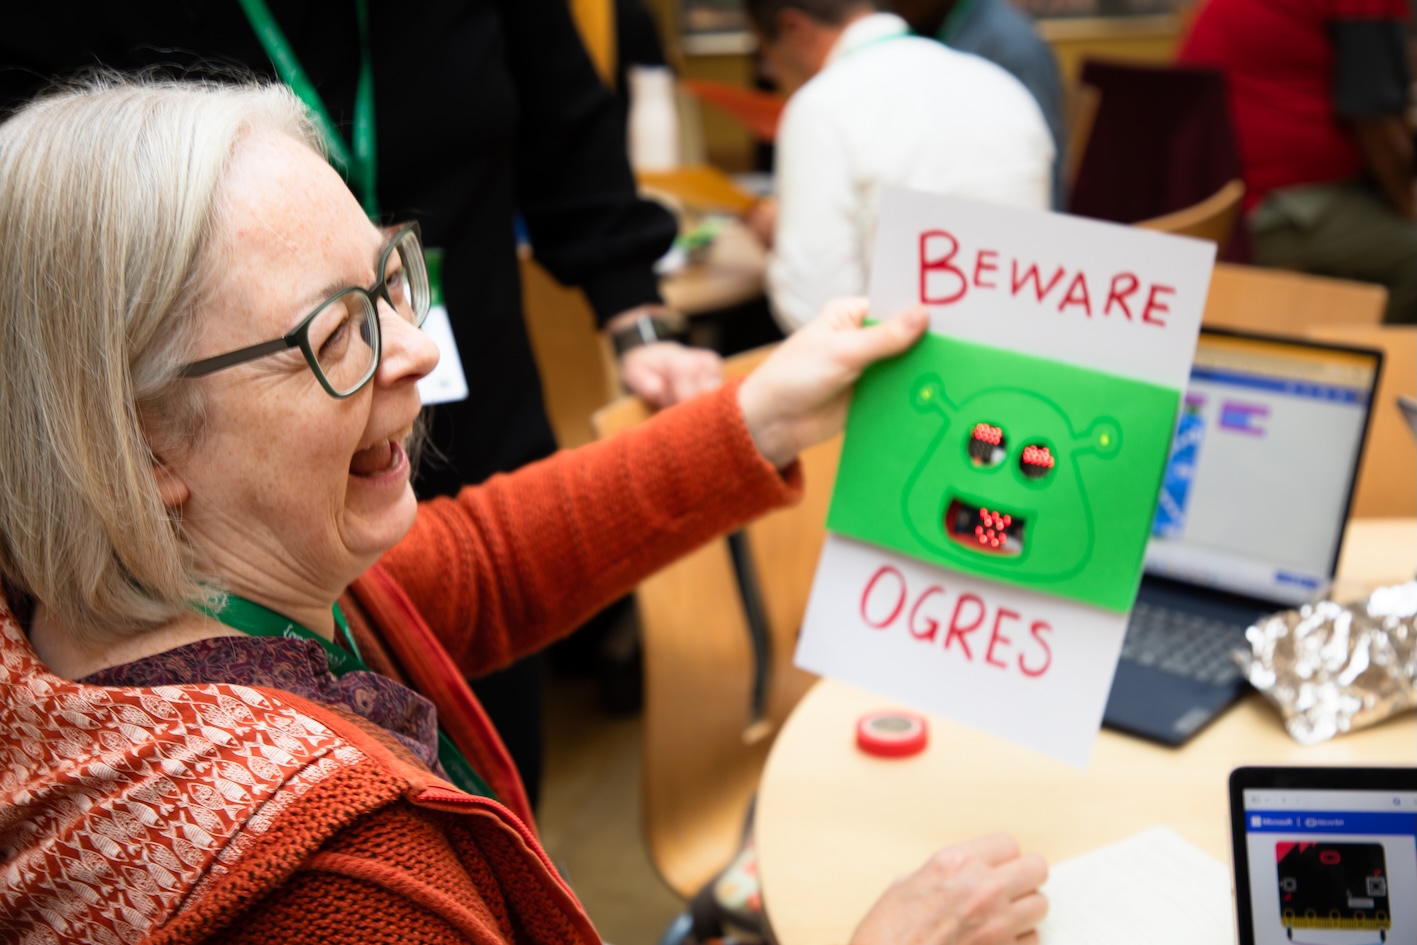
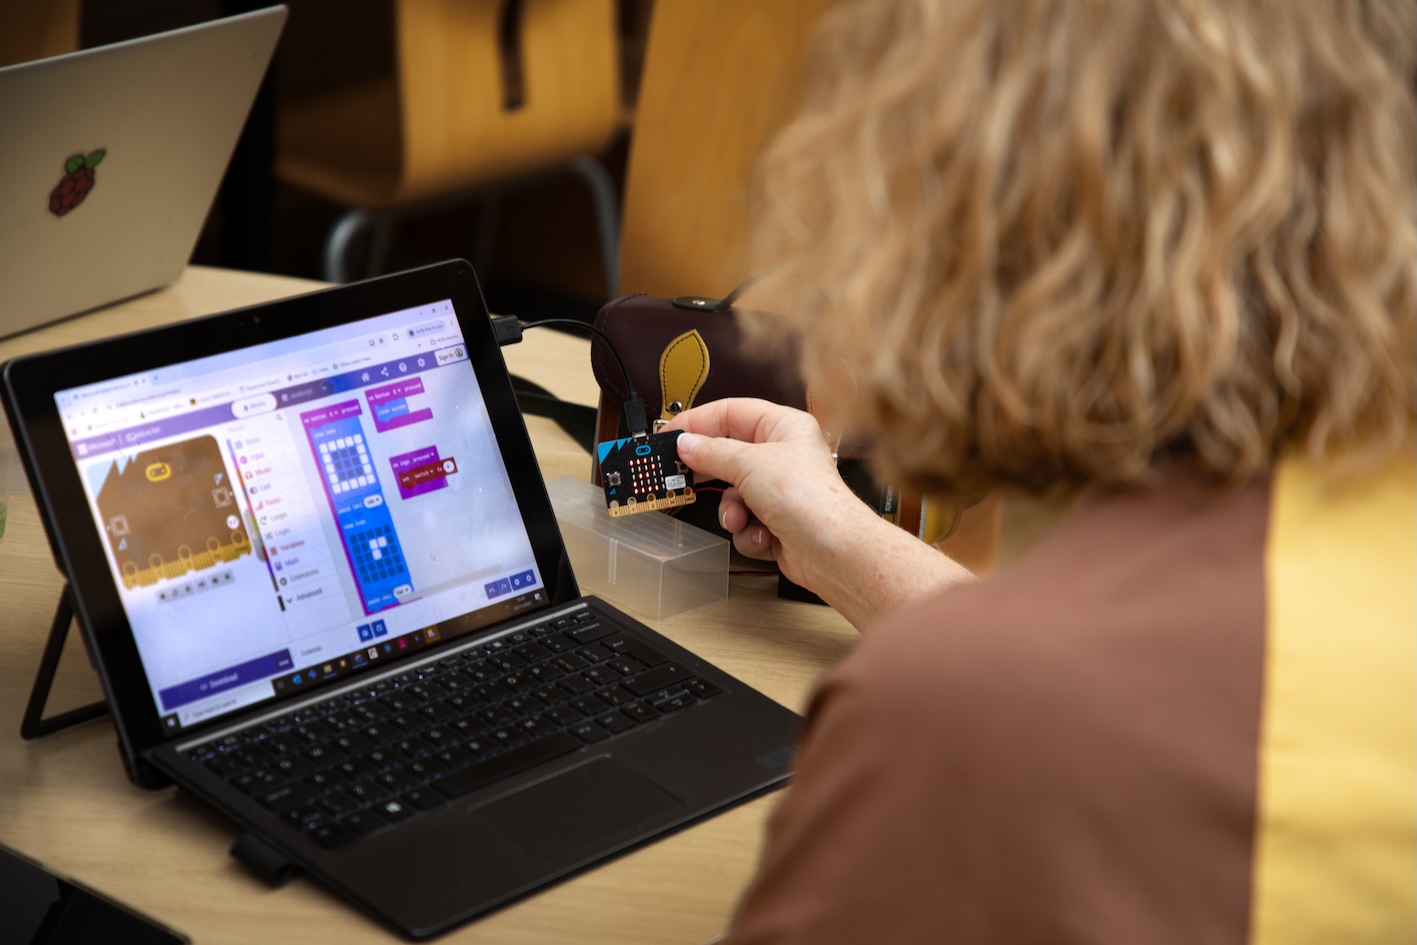
Over the first weekend in November, members of the global Code Club community came together for two inspiring days of learning, creativity and connection. The annual event celebrates the people who make Code Clubs happen, allowing them to share ideas, explore new tools, and connect with others who help young people learn to code.
Exploring new technologies and inclusive teaching
Saturday began with hands-on sessions that brought creativity and technology together, exploring large language models and prompt engineering in Collaborating with LLMs and being a prompt boss. There was a lot of laughter from attendees about how large language models can produce confident but incorrect answers if given vague prompts, but many left inspired to experiment with new technologies in their own clubs.
“First time there and it was amazing. Met loads of great people and the amazing code club crew. I learnt loads of new skills around AI and Arduino.” – An attendee
Collaboration that counts brought mentors together to discuss common challenges like volunteer retention, limited resources, and communication barriers. A crowd favourite was a shared volunteer toolkit, as well as event checklists and safeguarding resources.
“What I enjoyed most about the Clubs Conference was the opportunity to meet other facilitators and hear their stories — their successes and challenges. These conversations validated the volunteer work I do and reminded me of the impact of our clubs.” – An attendee
From the theatre sessions, you can watch Inclusive learning – Supporting Deaf learners in clubs which was both moving and insightful. We learnt that visual demonstrations, colour cues, and repetition were key to supporting Deaf learners. One memorable quote captured the spirit of the session:
“The children couldn’t speak to us. The children — we couldn’t hear their voices but by the eighth week we were able to hear their voices from what they built on the screen and it was echoing all around the classroom.” – Chidi Duru
The weekend’s talks showcased the reach of Code Club worldwide, with volunteers sharing their experiences of collaboration, sustainability, and creativity.
WatchLessons from resourceful Code Clubs in India, which highlighted the ingenuity of young learners in under-resourced settings, while Hands-on with the Raspberry Pi Pico showcased low-cost, high-impact projects from Kenya and South Africa.
Speakers showed how community clubs adapt to local needs with unplugged activities and coding games inspired by cricket and kabaddi, empowering young people to solve real problems and celebrate curiosity through play. Excitingly, these new resources will be launching early next year; keep an eye on our activities page to be among the first to try them out!
In the session Code Club Projects Unplugged, facilitators shared the idea of “hiding the vegetables” — hiding the learning inside the fun. Whether through a collaborative Scratch game, a micro:bit prop on stage, or a Pico gadget solving a real problem, this approach helps young people learn through play. They remember the joy, and the skills come naturally.
Learning beyond the screen
Teaching tech away from the computer screen shared a fun unplugged cybersecurity activity, The Chicken Shop, where learners role-play social engineering scenarios. Its success came from clear printed instructions, movement, humour, and strong debriefing.
Learning coding outside the box explored how to engage young people with diverse learning styles while the Arduino crash course gave attendees a taste of physical computing and C++ programming in action. Workshops on AI, sustainability, and youth empowerment with Raspberry Pi computers and Unlocking Code Club resources helped club leaders discover practical ways to inspire problem-solving and make use of all the support available through Code Club.
The message from the sessions was clear: young people learn best when technology is human and hands-on.
Showcasing creativity with Coolest Projects
Coolest Projects – get involved!championed creativity over competition. Any young person under 18 can submit their project, including unfinished ideas. In-person and online showcases celebrate progress, imagination, and teamwork.
Speaking on the closing panel, Code Club leader Rachael Coultart talked about the importance of Coolest Projects as a rare platform for children to talk about their learning. She spoke about the experience of one particular child, explaining that it had made a powerful impression on her, saying:
“It had such a huge impact. I felt so proud of her and what she’d achieved. Afterwards, her parents told me that they felt it was the first time she had really been seen.”
What the community is taking forward
The community is united in its commitment to making Code Clubs inclusive, creative, and sustainable.
Context matters — projects that reflect local interests and challenges motivate young people to learn
Accessibility is central: visual cues, repetition, interpreters, and inclusive resources support every learner
Structure builds confidence; start with simple, guided activities before open-ended exploration
Volunteers are vital; shared toolkits, checklists, and training help them deliver engaging sessions
Celebration and affordability matter too: regular showcases and tools like the micro:bit, Pico, and Crumble keep computing fun, hands-on, and accessible for all
“Thank you. Clubs Conference is a highlight of my year.” – An attendee
Stay connected
If you want to stay up to date with the latest news, events and opportunities from Code Club, sign up for our newsletter and be part of the growing global community.
On 18 November 2025 at 11:20 UTC (all times in this blog are UTC), Cloudflare’s network began experiencing significant failures to deliver core network traffic. This showed up to Internet users trying to access our customers’ sites as an error page indicating a failure within Cloudflare’s network.
The issue was not caused, directly or indirectly, by a cyber attack or malicious activity of any kind. Instead, it was triggered by a change to one of our database systems’ permissions which caused the database to output multiple entries into a “feature file” used by our Bot Management system. That feature file, in turn, doubled in size. The larger-than-expected feature file was then propagated to all the machines that make up our network.
The software running on these machines to route traffic across our network reads this feature file to keep our Bot Management system up to date with ever changing threats. The software had a limit on the size of the feature file that was below its doubled size. That caused the software to fail.
After we initially wrongly suspected the symptoms we were seeing were caused by a hyper-scale DDoS attack, we correctly identified the core issue and were able to stop the propagation of the larger-than-expected feature file and replace it with an earlier version of the file. Core traffic was largely flowing as normal by 14:30. We worked over the next few hours to mitigate increased load on various parts of our network as traffic rushed back online. As of 17:06 all systems at Cloudflare were functioning as normal.
We are sorry for the impact to our customers and to the Internet in general. Given Cloudflare’s importance in the Internet ecosystem any outage of any of our systems is unacceptable. That there was a period of time where our network was not able to route traffic is deeply painful to every member of our team. We know we let you down today.
This post is an in-depth recount of exactly what happened and what systems and processes failed. It is also the beginning, though not the end, of what we plan to do in order to make sure an outage like this will not happen again.
The outage
The chart below shows the volume of 5xx error HTTP status codes served by the Cloudflare network. Normally this should be very low, and it was right up until the start of the outage.
The volume prior to 11:20 is the expected baseline of 5xx errors observed across our network. The spike, and subsequent fluctuations, show our system failing due to loading the incorrect feature file. What’s notable is that our system would then recover for a period. This was very unusual behavior for an internal error.
The explanation was that the file was being generated every five minutes by a query running on a ClickHouse database cluster, which was being gradually updated to improve permissions management. Bad data was only generated if the query ran on a part of the cluster which had been updated. As a result, every five minutes there was a chance of either a good or a bad set of configuration files being generated and rapidly propagated across the network.
This fluctuation made it unclear what was happening as the entire system would recover and then fail again as sometimes good, sometimes bad configuration files were distributed to our network. Initially, this led us to believe this might be caused by an attack. Eventually, every ClickHouse node was generating the bad configuration file and the fluctuation stabilized in the failing state.
Errors continued until the underlying issue was identified and resolved starting at 14:30. We solved the problem by stopping the generation and propagation of the bad feature file and manually inserting a known good file into the feature file distribution queue. And then forcing a restart of our core proxy.
The remaining long tail in the chart above is our team restarting remaining services that had entered a bad state, with 5xx error code volume returning to normal at 17:06.
The following services were impacted:
Service / Product
Impact description
Core CDN and security services
HTTP 5xx status codes. The screenshot at the top of this post shows a typical error page delivered to end users.
Turnstile
Turnstile failed to load.
Workers KV
Workers KV returned a significantly elevated level of HTTP 5xx errors as requests to KV’s “front end” gateway failed due to the core proxy failing.
Dashboard
While the dashboard was mostly operational, most users were unable to log in due to Turnstile being unavailable on the login page.
Email Security
While email processing and delivery were unaffected, we observed a temporary loss of access to an IP reputation source which reduced spam-detection accuracy and prevented some new-domain-age detections from triggering, with no critical customer impact observed. We also saw failures in some Auto Move actions; all affected messages have been reviewed and remediated.
Access
Authentication failures were widespread for most users, beginning at the start of the incident and continuing until the rollback was initiated at 13:05. Any existing Access sessions were unaffected.
All failed authentication attempts resulted in an error page, meaning none of these users ever reached the target application while authentication was failing. Successful logins during this period were correctly logged during this incident.
Any Access configuration updates attempted at that time would have either failed outright or propagated very slowly. All configuration updates are now recovered.
As well as returning HTTP 5xx errors, we observed significant increases in latency of responses from our CDN during the impact period. This was due to large amounts of CPU being consumed by our debugging and observability systems, which automatically enhance uncaught errors with additional debugging information.
How Cloudflare processes requests, and how this went wrong today
Every request to Cloudflare takes a well-defined path through our network. It could be from a browser loading a webpage, a mobile app calling an API, or automated traffic from another service. These requests first terminate at our HTTP and TLS layer, then flow into our core proxy system (which we call FL for “Frontline”), and finally through Pingora, which performs cache lookups or fetches data from the origin if needed.
We previously shared more detail about how the core proxy works here.
As a request transits the core proxy, we run the various security and performance products available in our network. The proxy applies each customer’s unique configuration and settings, from enforcing WAF rules and DDoS protection to routing traffic to the Developer Platform and R2. It accomplishes this through a set of domain-specific modules that apply the configuration and policy rules to traffic transiting our proxy.
One of those modules, Bot Management, was the source of today’s outage.
Cloudflare’s Bot Management includes, among other systems, a machine learning model that we use to generate bot scores for every request traversing our network. Our customers use bot scores to control which bots are allowed to access their sites — or not.
The model takes as input a “feature” configuration file. A feature, in this context, is an individual trait used by the machine learning model to make a prediction about whether the request was automated or not. The feature configuration file is a collection of individual features.
This feature file is refreshed every few minutes and published to our entire network and allows us to react to variations in traffic flows across the Internet. It allows us to react to new types of bots and new bot attacks. So it’s critical that it is rolled out frequently and rapidly as bad actors change their tactics quickly.
A change in our underlying ClickHouse query behaviour (explained below) that generates this file caused it to have a large number of duplicate “feature” rows. This changed the size of the previously fixed-size feature configuration file, causing the bots module to trigger an error.
As a result, HTTP 5xx error codes were returned by the core proxy system that handles traffic processing for our customers, for any traffic that depended on the bots module. This also affected Workers KV and Access, which rely on the core proxy.
Unrelated to this incident, we were and are currently migrating our customer traffic to a new version of our proxy service, internally known as FL2. Both versions were affected by the issue, although the impact observed was different.
Customers deployed on the new FL2 proxy engine, observed HTTP 5xx errors. Customers on our old proxy engine, known as FL, did not see errors, but bot scores were not generated correctly, resulting in all traffic receiving a bot score of zero. Customers that had rules deployed to block bots would have seen large numbers of false positives. Customers who were not using our bot score in their rules did not see any impact.
Throwing us off and making us believe this might have been an attack was another apparent symptom we observed: Cloudflare’s status page went down. The status page is hosted completely off Cloudflare’s infrastructure with no dependencies on Cloudflare. While it turned out to be a coincidence, it led some of the team diagnosing the issue to believe that an attacker may be targeting both our systems as well as our status page. Visitors to the status page at that time were greeted by an error message:
In the internal incident chat room, we were concerned that this might be the continuation of the recent spate of high volume AisuruDDoS attacks:
The query behaviour change
I mentioned above that a change in the underlying query behaviour resulted in the feature file containing a large number of duplicate rows. The database system in question uses ClickHouse’s software.
For context, it’s helpful to know how ClickHouse distributed queries work. A ClickHouse cluster consists of many shards. To query data from all shards, we have so-called distributed tables (powered by the table engine Distributed) in a database called default. The Distributed engine queries underlying tables in a database r0. The underlying tables are where data is stored on each shard of a ClickHouse cluster.
Queries to the distributed tables run through a shared system account. As part of efforts to improve our distributed queries security and reliability, there’s work being done to make them run under the initial user accounts instead.
Before today, ClickHouse users would only see the tables in the default database when querying table metadata from ClickHouse system tables such as system.tables or system.columns.
Since users already have implicit access to underlying tables in r0, we made a change at 11:05 to make this access explicit, so that users can see the metadata of these tables as well. By making sure that all distributed subqueries can run under the initial user, query limits and access grants can be evaluated in a more fine-grained manner, avoiding one bad subquery from a user affecting others.
The change explained above resulted in all users accessing accurate metadata about tables they have access to. Unfortunately, there were assumptions made in the past, that the list of columns returned by a query like this would only include the “default” database:
SELECT

  name,

  type

FROM system.columns

WHERE

  table = 'http_requests_features'

order by name;
Note how the query does not filter for the database name. With us gradually rolling out the explicit grants to users of a given ClickHouse cluster, after the change at 11:05 the query above started returning “duplicates” of columns because those were for underlying tables stored in the r0 database.
This, unfortunately, was the type of query that was performed by the Bot Management feature file generation logic to construct each input “feature” for the file mentioned at the beginning of this section.
The query above would return a table of columns like the one displayed (simplified example):
However, as part of the additional permissions that were granted to the user, the response now contained all the metadata of the r0 schema effectively more than doubling the rows in the response ultimately affecting the number of rows (i.e. features) in the final file output.
Memory preallocation
Each module running on our proxy service has a number of limits in place to avoid unbounded memory consumption and to preallocate memory as a performance optimization. In this specific instance, the Bot Management system has a limit on the number of machine learning features that can be used at runtime. Currently that limit is set to 200, well above our current use of ~60 features. Again, the limit exists because for performance reasons we preallocate memory for the features.
When the bad file with more than 200 features was propagated to our servers, this limit was hit — resulting in the system panicking. The FL2 Rust code that makes the check and was the source of the unhandled error is shown below:
This resulted in the following panic which in turn resulted in a 5xx error:
thread fl2_worker_thread panicked: called Result::unwrap() on an Err value
Other impact during the incident
Other systems that rely on our core proxy were impacted during the incident. This included Workers KV and Cloudflare Access. The team was able to reduce the impact to these systems at 13:04, when a patch was made to Workers KV to bypass the core proxy. Subsequently, all downstream systems that rely on Workers KV (such as Access itself) observed a reduced error rate.
The Cloudflare Dashboard was also impacted due to both Workers KV being used internally and Cloudflare Turnstile being deployed as part of our login flow.
Turnstile was impacted by this outage, resulting in customers who did not have an active dashboard session being unable to log in. This showed up as reduced availability during two time periods: from 11:30 to 13:10, and between 14:40 and 15:30, as seen in the graph below.
The first period, from 11:30 to 13:10, was due to the impact to Workers KV, which some control plane and dashboard functions rely upon. This was restored at 13:10, when Workers KV bypassed the core proxy system.
The second period of impact to the dashboard occurred after restoring the feature configuration data. A backlog of login attempts began to overwhelm the dashboard. This backlog, in combination with retry attempts, resulted in elevated latency, reducing dashboard availability. Scaling control plane concurrency restored availability at approximately 15:30.
Remediation and follow-up steps
Now that our systems are back online and functioning normally, work has already begun on how we will harden them against failures like this in the future. In particular we are:
Hardening ingestion of Cloudflare-generated configuration files in the same way we would for user-generated input
Enabling more global kill switches for features
Eliminating the ability for core dumps or other error reports to overwhelm system resources
Reviewing failure modes for error conditions across all core proxy modules
Today was Cloudflare’s worst outage since 2019. We’ve had outages that have made our dashboard unavailable. Some that have caused newer features to not be available for a period of time. But in the last 6+ years we’ve not had another outage that has caused the majority of core traffic to stop flowing through our network.
An outage like today is unacceptable. We’ve architected our systems to be highly resilient to failure to ensure traffic will always continue to flow. When we’ve had outages in the past it’s always led to us building new, more resilient systems.
On behalf of the entire team at Cloudflare, I would like to apologize for the pain we caused the Internet today.
Time (UTC)
Status
Description
11:05
Normal.
Database access control change deployed.
11:28
Impact starts.
Deployment reaches customer environments, first errors observed on customer HTTP traffic.
11:32-13:05
The team investigated elevated traffic levels and errors to Workers KV service.
The initial symptom appeared to be degraded Workers KV response rate causing downstream impact on other Cloudflare services.
Mitigations such as traffic manipulation and account limiting were attempted to bring the Workers KV service back to normal operating levels.
The first automated test detected the issue at 11:31 and manual investigation started at 11:32. The incident call was created at 11:35.
13:05
Workers KV and Cloudflare Access bypass implemented — impact reduced.
During investigation, we used internal system bypasses for Workers KV and Cloudflare Access so they fell back to a prior version of our core proxy. Although the issue was also present in prior versions of our proxy, the impact was smaller as described below.
13:37
Work focused on rollback of the Bot Management configuration file to a last-known-good version.
We were confident that the Bot Management configuration file was the trigger for the incident. Teams worked on ways to repair the service in multiple workstreams, with the fastest workstream a restore of a previous version of the file.
14:24
Stopped creation and propagation of new Bot Management configuration files.
We identified that the Bot Management module was the source of the 500 errors and that this was caused by a bad configuration file. We stopped automatic deployment of new Bot Management configuration files.
14:24
Test of new file complete.
We observed successful recovery using the old version of the configuration file and then focused on accelerating the fix globally.
14:30
Main impact resolved. Downstream impacted services started observing reduced errors.
A correct Bot Management configuration file was deployed globally and most services started operating correctly.
17:06
All services resolved. Impact ends.
All downstream services restarted and all operations fully restored.
Already on Sep 17 we released systemd v258 into the wild.
In the weeks leading up to that release I have posted a series of
serieses of posts to Mastodon about key new features in this release,
under the #systemd258 hash
tag. It was my intention to post a link list here on this blog right
after completing that series, but I simply forgot! Hence, in case you
aren’t using Mastodon, but would like to read up, here’s a list of all
37 posts:
I intend to do a similar series of serieses of posts for the next systemd
release (v259), hence if you haven’t left tech Twitter for Mastodon yet, now is
the opportunity.
We intend to shorten the release cycle a bit for the future, and in
fact managed to tag v259-rc1 already yesterday, just 2 months after
v258. Hence, my series for v259 will begin soon, under the #systemd259 hash tag.
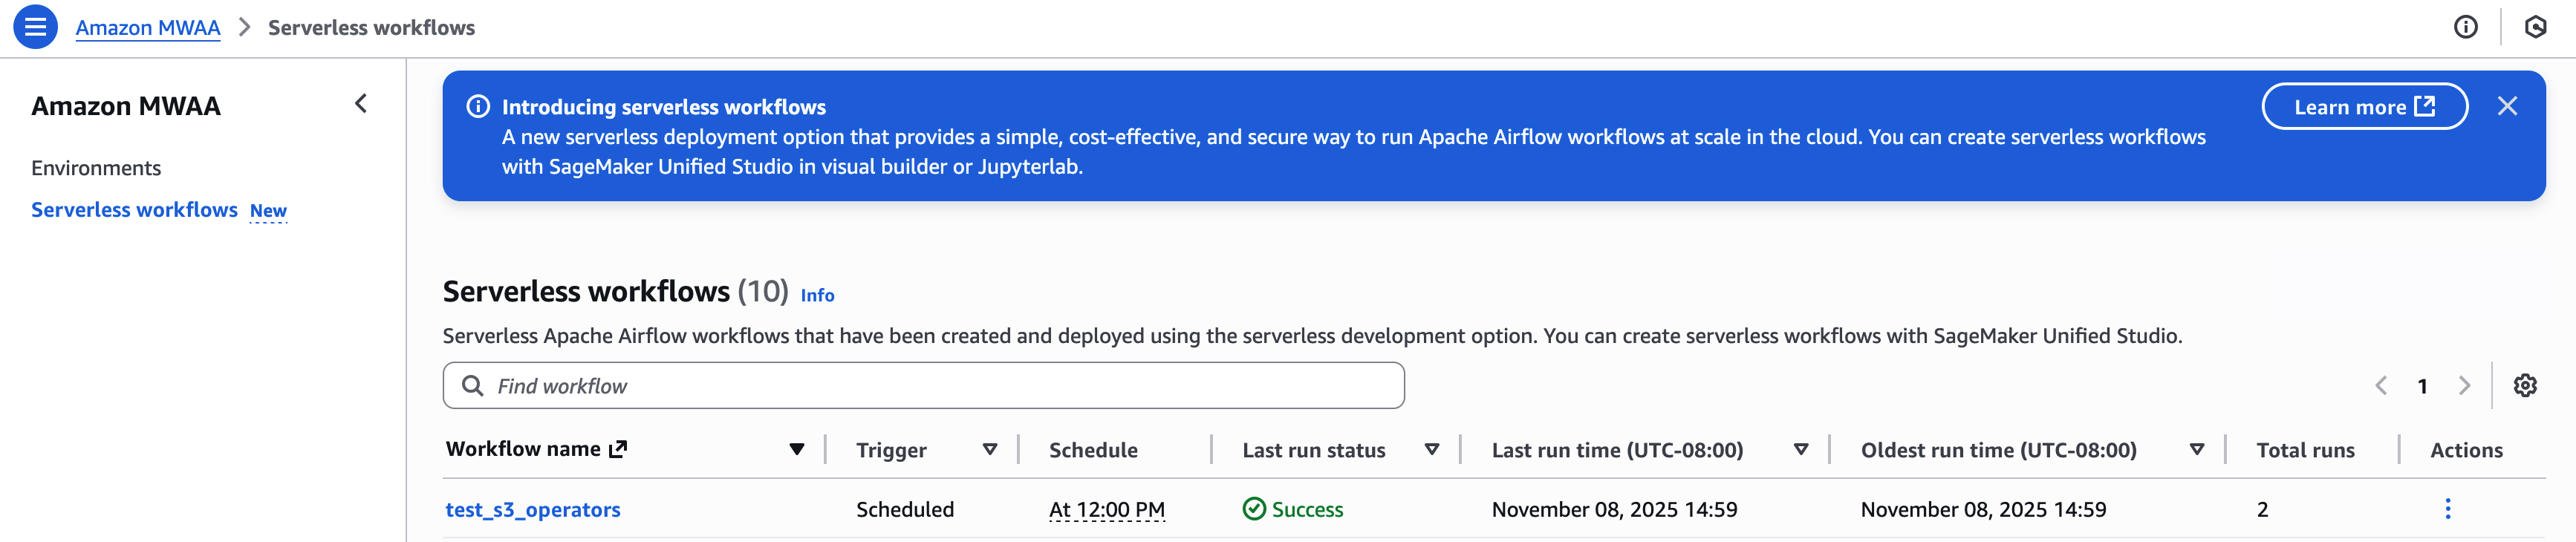
Today, AWS announced Amazon Managed Workflows for Apache Airflow (MWAA) Serverless. This is a new deployment option for MWAA that eliminates the operational overhead of managing Apache Airflow environments while optimizing costs through serverless scaling. This new offering addresses key challenges that data engineers and DevOps teams face when orchestrating workflows: operational scalability, cost optimization, and access management.
With MWAA Serverless you can focus on your workflow logic rather than monitoring for provisioned capacity. You can now submit your Airflow workflows for execution on a schedule or on demand, paying only for the actual compute time used during each task’s execution. The service automatically handles all infrastructure scaling so that your workflows run efficiently regardless of load.
Beyond simplified operations, MWAA Serverless introduces an updated security model for granular control through AWS Identity and Access Management (IAM). Each workflow can now have its own IAM permissions, running on a VPC of your choosing so you can implement precise security controls without creating separate Airflow environments. This approach significantly reduces security management overhead while strengthening your security posture.
In this post, we demonstrate how to use MWAA Serverless to build and deploy scalable workflow automation solutions. We walk through practical examples of creating and deploying workflows, setting up observability through Amazon CloudWatch, and converting existing Apache Airflow DAGs (Directed Acyclic Graphs) to the serverless format. We also explore best practices for managing serverless workflows and show you how to implement monitoring and logging.
How does MWAA Serverless work?
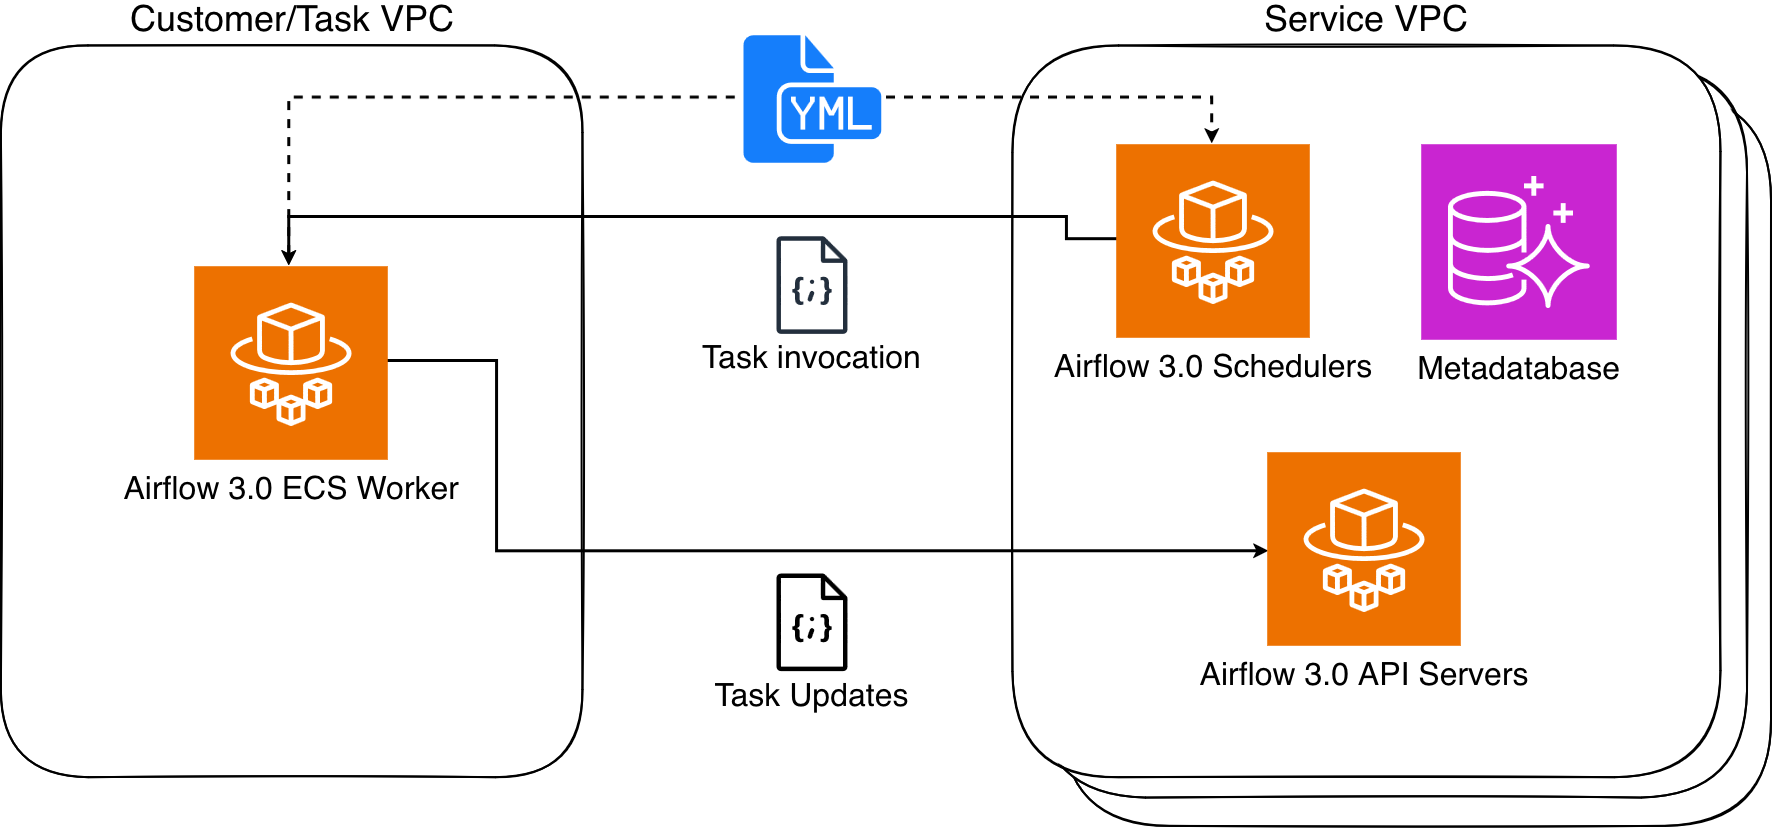
MWAA Serverless processes your workflow definitions and executes them efficiently in service-managed Airflow environments, automatically scaling resources based on workflow demands. MWAA Serverless uses the Amazon Elastic Container Service (Amazon ECS) executor to run each individual task on its own ECS Fargate container, on either your VPC or a service-managed VPC. Those containers then communicate back to their assigned Airflow cluster using the Airflow 3 Task API.
Figure 1: Amazon MWAA Architecture
MWAA Serverless uses declarative YAML configuration files based on the popular open source DAG Factory format to enhance security through task isolation. You have two options for creating these workflow definitions:
Write your workflows directly in YAML using AWS managed operators from the Amazon Provider Package
This declarative approach provides two key benefits. First, since MWAA Serverless reads workflow definitions from YAML it can determine task scheduling without running any workflow code. Second, this allows MWAA Serverless to grant execution permissions only when tasks run, rather than requiring broad permissions at the workflow level. The result is a more secure environment where task permissions are precisely scoped and time limited.
Service considerations for MWAA Serverless
MWAA Serverless has the following limitations that you should consider when deciding between serverless and provisioned MWAA deployments:
Operator support
MWAA Serverless only supports operators from the Amazon Provider Package.
To execute custom code or scripts, you’ll need to use AWS services, such as:
Note: Throughout this post, we use example values that you’ll need to replace with your own:
Replace amzn-s3-demo-bucket with your S3 bucket name
Replace 111122223333 with your AWS account number
Replace us-east-2 with your AWS Region. MWAA Serverless is available in multiple AWS Regions. Check the List of AWS Services Available by Region for current availability.
Creating your first serverless workflow
Let’s start by defining a simple workflow that gets a list of S3 objects and writes that list to a file in the same bucket. Create a new file called simple_s3_test.yaml with the following content:
For this workflow to run, you must create an Execution role that has permissions to list and write to the above bucket. The role also needs to be assumable from MWAA Serverless. The following CLI commands create this role and its associated policy:
AWS has published a conversion tool that uses the open-source Airflow DAG processor to serialize Python DAGs into YAML DAG factory format. To install, you run the following:
Note that, because the YAML conversion is done after the DAG parsing, the loop that creates the tasks is run first and the resulting static list of tasks is written to the YAML document with their dependencies.
Migrating an MWAA environment’s DAGs to MWAA Serverless
You can take advantage of a provisioned MWAA environment to develop and test your workflows and then move them to serverless to run efficiently at scale. Further, if your MWAA environment is using compatible MWAA Serverless operators, then you can convert all of the environment’s DAGs at once. The first step is to allow MWAA Serverless to assume the MWAA Execution role via a trust relationship. This is a one-time operation for each MWAA Execution role, and can be performed manually in the IAM console or using an AWS CLI command as follows:
MWAA Serverless workflow execution status is returned via the GetWorkflowRun function. The results from that will return details for that particular run. If there are errors in the workflow definition, they are returned under RunDetail in the ErrorMessage field as in the following example:
MWAA Serverless task logs are stored in the CloudWatch log group /aws/mwaa-serverless/<workflow id>/ (where /<workflow id> is the same string as the unique workflow id in the ARN of the workflow). For specific task log streams, you will need to list the tasks for the workflow run and then get each task’s information. You can combine these operations into a single CLI command.
After completing these steps, verify in the AWS Management Console that all resources have been properly removed. Remember that CloudWatch Logs are retained by default and may need to be deleted separately if you want to remove all traces of your workflow executions.
If you encounter any errors during cleanup, verify you have the necessary permissions and that resources exist before attempting to delete them. Some resources may have dependencies that require them to be deleted in a specific order.
Conclusion
In this post, we explored Amazon MWAA Serverless, a new deployment option that simplifies Apache Airflow workflow management. We demonstrated how to create workflows using YAML definitions, convert existing Python DAGs to the serverless format, and monitor your workflows.
MWAA Serverless offers several key advantages:
No provisioning overhead
Pay-per-use pricing model
Automatic scaling based on workflow demands
Enhanced security through granular IAM permissions
Simplified workflow definitions using YAML
To learn more MWAA Serverless, review the documentation.
Version 2.52.0 of the Git
source-code management system has been released. Changes include a new last-modified command to find the closest ancestor commit that
touched one or more paths, a couple of git refs improvements, a
new git repo command for obtaining information about the
repository itself, and more. See the announcement and this
GitHub blog entry for more information.
As outlined in the AWS post-quantum cryptography migration plan, establishing quantum-resistant roots of trust is critical for systems that need to maintain security for extended periods of time. ML-DSA, a signature scheme standardized in FIPS 204, provides quantum resistance while maintaining the performance characteristics needed for deployments at scale.
Previously, we shared how to use AWS Private CA and AWS KMS for code signing. In this post, we show you how to combine the post-quantum signing capability provided by AWS KMS with post-quantum code-signing PKI from AWS Private CA. Consumers of signed code that have been pre-provisioned with the post-quantum PKI roots can rest assured that the software could not have been forged by an adversary with a cryptographically relevant quantum computer (CRQC). For demonstration purposes, we use the diy-code-signing-kms-private-ca sample program, which uses the AWS SDK for Java. This code creates a PKI infrastructure, generates a code-signing certificate, signs binary code, and verifies the signature. Although we break down the steps to demonstrate the functionality in this post, you can run the Runner as-is to see it in action with commands found in the README file.
This post uses the Cryptographic Message Syntax (CMS) standard for encapsulating the signatures generated for input binary data. It stores the signature, X.509 certificate, and chain used to establish trust. The signature, known as a detached signature, doesn’t contain the original data. The detached signature can be used together with the original file, which was signed with standard tools such as OpenSSL natively to validate the authenticity of the file.
Create a post-quantum PKI hierarchy
For this post, we will use AWS Private CA to introduce a code-signing PKI. It will consist of a root CA to sign a subordinate CA, and a code-signing certificate signed by the subordinate CA. The whole chain will consist of quantum-resistant ML-DSA certificates.
CA hierarchy creation
First, the post-quantum CA hierarchy must be created with ML-DSA. In this example, we use the ML-DSA-65 variant of the post-quantum signature algorithm. You can do this with the AWS Java SDK as shown in the Runner.java file:
For code signing, you need an asymmetric key pair and a code-signing certificate. The asymmetric ML-DSA key pair is generated in AWS KMS and the code-signing certificate is issued by AWS Private CA.
Create an ML-DSA key pair in AWS KMS
First, you must create an asymmetric key pair for code signing operations. Similar to the creation of the hierarchy, the AWS Java SDK can be used to create that AWS KMS key (key pair). Signing will be taking place with the key pair’s private key in AWS KMS. The corresponding public key will be in the code-signing leaf certificate signed by the subordinate CA. These calls are performed as part of the main method within the Runner.java file:
Creating a certificate signing request (CSR) using AWS Private CA is a two-step process. First, you must create a CSR that contains both an identity (Subject) and the previously created AWS KMS public key. The following code snippet in Runner.java accomplishes this:
You can see that the CSR contains an ML-DSA-65 public key. Its corresponding private key will be used to sign code.
The CSR is used by the subordinate CA to issue the code-signing certificate. Note that the code-signing template is used in the templateArn of the IssueCertificate request in the relevant PrivateCA.java file. The inclusion of this template helps ensure that AWS Private CA will issue a certificate with the correct Key Usage (KU) and Extended Key Usage (EKU) extension values, regardless of the values presented in the CSR.
The response includes the ML-DSA-65 code-signing certificate. You can use OpenSSL 3.5 or later to inspect the contents of the certificate after you save it to a file named code-signing-cert.pem:
You can see that the certificate includes the ML-DSA-65 public key of the code-signing key pair and the ML-DSA-65 signature from the subordinate CA. You also see the KU and the EKU values, which represent a code-signing certificate from the AWS Private CA template.
Sign code
At this point, you have set up the code-signing PKI, have a code-signing certificate issued by AWS Private CA and a corresponding ML-DSA key pair residing in KMS.
The Java SDK can be used to generate a CMS signature for a code binary file. In the background, this is accomplished by calling the AWS KMS Sign API with the ML-DSA key pair as shown in Runner.java. The following is part of the Java code. This first snippet involves building a certificate chain and then using it along with the code-signing AWS KMS key, the signer’s certificate, and <DATA_TO_SIGN>, the byte array representation of the code file, to generate the detached signature in a CMS structure.
The CMS signature object directly encapsulates both the code-signing certificate and the subordinate CA certificate. It’s expected that the root certificate will reside in a customer-managed trust store. In addition to these certificates, the CMS object also contains the digest of the input data within the signedAttrs of the signerInfos in the ASN.1 structure. The digest algorithm is SHAKE256 and the OCTET STRING represents the binary digest itself. The use of ML-DSA in CMS is specified in RFC9882.
Note: Although this example uses one ML-DSA signature, some use cases might include dual signatures, a traditional and a quantum-resistant one. Such signed artifacts can be backwards compatible with legacy verifiers that support and can only verify the traditional signature. Upgraded verifiers can verify both signatures.
Verify signed code
Before loading a signed code artifact, its signature needs to be verified. That includes verifying the signature of the code and validating the certificate chain to the trusted root CA. The following code snippet from the main method within the file Runner.java is used for the certificate chain validation and the signature in the code object:
The preceding code retrieves the ML-DSA public key from the code-signing certificate; AWS access or credentials aren’t needed to validate the signature. Entities that have the root CA certificate loaded in their trust store can verify it without needing access to the AWS KMS verify API.
Note: The Runner.java implementation doesn’t use a certificate trust store that’s either part of a browser or part of a file system within the resident operating system of a device or a server. The trust store is placed in an instance of a Java class object for the purpose of this post. If you’re planning to use this code-signing example in a production system, you must change the implementation to use a trust store on the host. To do so, you can build and distribute a secure trust store that includes the root CA certificate.
Alternatively, OpenSSL 3.5 or later can be used to validate the detached signature of the provided input data file with root-ca-MLDSA65.pem, the provided root CA certificate from AWS Private CA.
Note: Although this post focused on code-signing, AWS Private CA can enable post-quantum ML-DSA authentication for other private PKI use cases. In one scenario, applications outside of AWS can access AWS resources by temporarily using certificate-based authentication and swapping it with AWS credentials with AWS IAM Roles Anywhere. AWS IAM Roles Anywhere now supports ML-DSA PKIs like the one created in this post. In another scenario, an mTLS client or IKEv2/IPsec peer could use an ML-DSA certificate issued by AWS Private CA to be authenticated by a server or peer respectively who has been pre-provisioned with the post-quantum PKI root certificate.
Conclusion
This announcement marks an important milestone for post-quantum authentication. With the introduction of ML-DSA X.509 certificates in AWS Private CA, customers can bring quantum resistance to their private PKI use cases. These use cases include client authentication for mTLS or IKEv2/IPsec tunnels, IAM Roles Anywhere, or applications that use private PKI authentication. ML-DSA certificates with AWS Private CA and signing with AWS KMS also enable post-quantum code-singing and establishing post-quantum long-lived roots of trust for devices designed to operate for a long time even after CRQCs became available. Learn more about post-quantum cryptography in general and the overall AWS plan to migrate to post-quantum cryptography.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Security, Identity, & Compliance re:Post or contact AWS Support. For more details regarding AWS PQC efforts, refer to our PQC page.
The weeks before AWS re:Invent, my team is full steam ahead preparing content for the conference. I can’t wait to meet you at one of my three talks: CMP346 : Supercharge AI/ML on Apple Silicon with EC2 Mac, CMP344: Speed up Apple application builds with CI/CD on EC2 Mac, and DEV416: Develop your AI Agents and MCP Tools in Swift.
Last week, AWS announced three new AWS Heroes. The AWS Heroes program recognizes a vibrant, worldwide group of AWS experts whose enthusiasm for knowledge-sharing has a real impact within the community. Welcome to the community, Dimple, Rola, and Vivek.
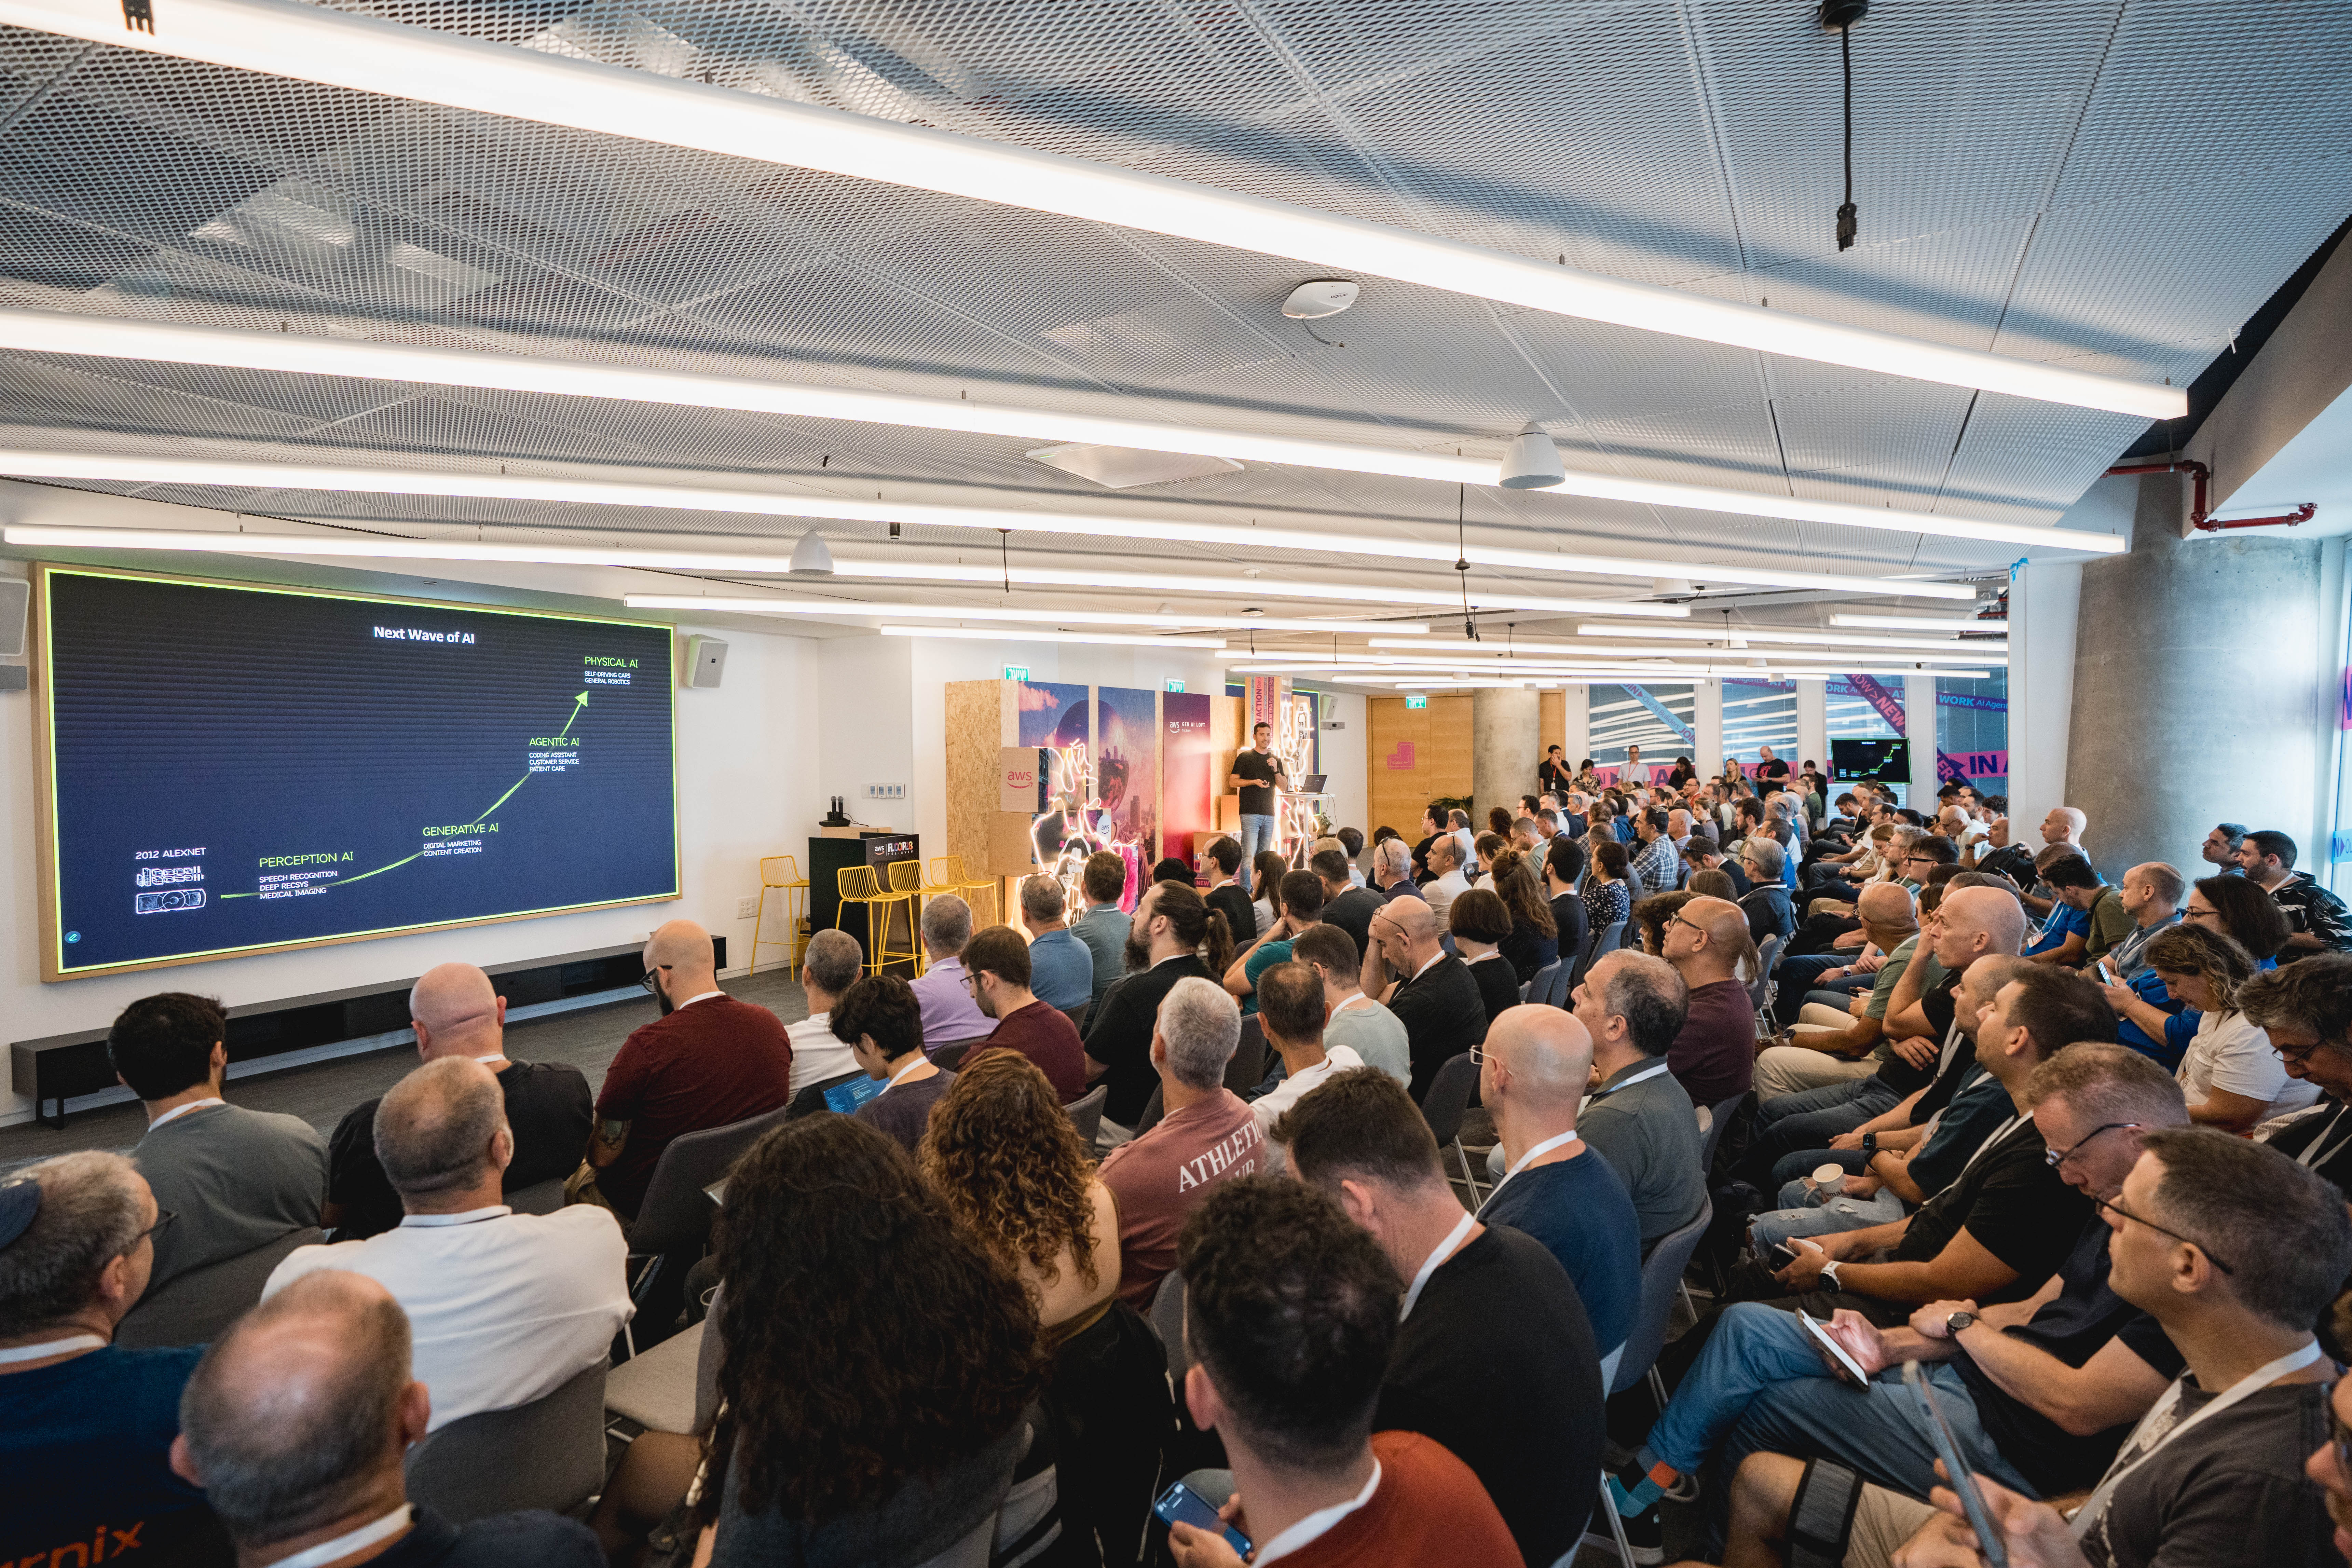
We also opened the GenAI Loft in Tel Aviv, Israel. AWS Gen AI Lofts are collaborative spaces and immersive experiences for startups and developers. The Loft content is tailored to address local customer needs – from startups and enterprises to public sector organizations, bringing together developers, investors, and industry experts under one roof.
AWS Network Load Balancer (NLB) now supports QUIC protocol in passthrough mode – This provides ultra-low latency traffic forwarding with session stickiness using QUIC Connection IDs. This capability reduces application latency by 25-30% for mobile-first applications through minimized handshakes and connection resilience. NLB operates in passthrough mode, forwarding QUIC traffic directly to targets while maintaining customer control over TLS certificates and end-to-end encryption. The blog post has the details.
Application Load Balancer (ALB) support client credential flow with JWT verification – This one is important for API developers too. This simplifies the deployment of secure machine-to-machine (M2M) and service-to-service (S2S) communications. This provides ALB with the ability to verify JWTs, reducing architectural complexity and simplifying security implementation.
AWS KMS now supports Edwards-curve Digital Signature Algorithm (EdDSA) – This capability provides 128-bit security equivalent to NIST P-256 with faster signing performance and compact sizes (64-byte signatures, 32-byte public keys). Ed25519 is ideal for IoT devices and blockchain applications requiring small key and signature sizes.
Amazon DCV now supports Amazon EC2 Mac instances – This provides high-performance remote desktop access with 4K resolution and 60 FPS performance. You can connect from Windows, Linux, macOS, or web clients with features including time zone redirection and audio output.
Make your web apps hands-free with Amazon Nova Sonic – Amazon Nova Sonic, a foundation model from AAmazon Bedrock, provides you with the ability to create natural, low-latency, bidirectional speech conversations for applications. This provides users with the ability to collaborate with applications through voice and embedded intelligence, unlocking new interaction patterns and enhancing usability. This blog post demonstrates a reference app, Smart Todo App. It shows how voice can be integrated to provide a hands-free experience for task management.
AWS X-Ray SDKs & Daemon migration to OpenTelemetry – AWS X-Ray is transitioning to OpenTelemetry as its primary instrumentation standard for application tracing. OpenTelemetry-based instrumentation solutions are recommended for producing traces from applications and sending them to AWS X-Ray. X-Ray’s existing console experience and functionality continue to be fully supported and remains unchanged by this transition.
Powering the world’s largest events: How Amazon CloudFront delivers at scale – Amazon CloudFront achieved a record-breaking peak of 268 terabits per second on November 1, 2025, during major game delivery workloads—enough bandwidth to simultaneously stream live sports in HD to approximately 45 million concurrent viewers. This milestone demonstrates the CloudFront massive scale, powered by 750+ edge locations across 440+ cities globally and 1,140+ embedded PoPs within 100+ ISPs, with the latest generation delivering 3x the performance of previous versions.
Upcoming AWS events Check your calendars so that you can sign up for these upcoming events:
AWS Builder Loft – A community tech space in San Francisco where you can learn from expert sessions, join hands-on workshops, explore AI and emerging technologies, and collaborate with other builders to accelerate your ideas. Browse the upcoming sessions and join the events that interest you.
AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by experienced AWS users and industry leaders from around the world. I will deliver the opening keynote at the last Community Day of the year in Kinshasa, Democratic Republic of Congo (November 22). The next Community Day will be in Timişoara, România (April 2026). The call for papers is now open.
For better or for worse, the NUMA node is the abstraction used by the
kernel to keep track of different types of memory. How that abstraction is
used, though, is still an active area of development. Two patch sets
focused on this problem are currently under review; one addresses the
perennial problem of promoting heavily used folios from slower to faster
memory, while the other aims to improve the kernel’s handling of nodes
containing special memory installed for a specific purpose.
The Debian Libre Live Images project provides Live ISO images for
Intel/AMD-compatible 64-bit x86 CPUs (amd64) built without any
non-free software, suitable for running and installing Debian. The
images are similar to the Debian Live Images
distributed as Debian
live images.
He does warn that this is a first public release, so there may be
problems. See the current
list of known issues before trying the images out.
Security updates have been issued by Debian (gst-plugins-base1.0, lasso, and thunderbird), Fedora (bind9-next, chromium, containerd, fvwm3, luksmeta, opentofu, python-pdfminer, python-uv-build, ruff, rust-get-size-derive2, rust-get-size2, rust-regex, rust-regex-automata, rust-reqsign, rust-reqsign-aws-v4, rust-reqsign-command-execute-tokio, rust-reqsign-core, rust-reqsign-file-read-tokio, rust-reqsign-http-send-reqwest, suricata, uv, and xmedcon), Mageia (apache-commons-beanutils, apache-commons-fileupload, apache-commons-lang, botan2, python-django, spdlog, stardict, webkit2, and yelp-xsl), Slackware (xpdf), and SUSE (bind, chromedriver, firefox, kernel, libxml2, and openssh).
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.