Security updates have been issued by Debian (nginx and ruby-rack), Fedora (expat and libxslt), Mageia (bluez, dcmtk, ffmpeg, and radare2), Red Hat (container-tools:rhel8, gvisor-tap-vsock, kernel, kernel-rt, libreoffice, and podman), SUSE (buildah, forgejo, gitleaks, google-guest-agent, google-osconfig-agent, govulncheck-vulndb, grafana, helm, libxslt, php8, python-gunicorn, and python-Jinja2), and Ubuntu (freerdp2 and varnish).
Cloudflare has a new feature—available to free users as well—that uses AI to generate random pages to feed to AI web crawlers:
Instead of simply blocking bots, Cloudflare’s new system lures them into a “maze” of realistic-looking but irrelevant pages, wasting the crawler’s computing resources. The approach is a notable shift from the standard block-and-defend strategy used by most website protection services. Cloudflare says blocking bots sometimes backfires because it alerts the crawler’s operators that they’ve been detected.
“When we detect unauthorized crawling, rather than blocking the request, we will link to a series of AI-generated pages that are convincing enough to entice a crawler to traverse them,” writes Cloudflare. “But while real looking, this content is not actually the content of the site we are protecting, so the crawler wastes time and resources.”
The company says the content served to bots is deliberately irrelevant to the website being crawled, but it is carefully sourced or generated using real scientific facts—such as neutral information about biology, physics, or mathematics—to avoid spreading misinformation (whether this approach effectively prevents misinformation, however, remains unproven).
It’s basically an AI-generated honeypot. And AI scraping is a growing problem:
The scale of AI crawling on the web appears substantial, according to Cloudflare’s data that lines up with anecdotal reports we’ve heard from sources. The company says that AI crawlers generate more than 50 billion requests to their network daily, amounting to nearly 1 percent of all web traffic they process. Many of these crawlers collect website data to train large language models without permission from site owners….
Presumably the crawlers will now have to up both their scraping stealth and their ability to filter out AI-generated content like this. Which means the honeypots will have to get better at detecting scrapers and more stealthy in their fake content. This arms race is likely to go back and forth, wasting a lot of energy in the process.
With Cloudflare’s victory against patent trolls Sable IP and Sable Networks in the books, it’s time to close out the case’s Project Jengo competition.
In our last update, we talked about the conclusion of Sable’s 3+ year campaign to extort a payment from Cloudflare based on meritless patent infringement claims. After Cloudflare’s victory at trial in February 2024, Sable finally — and fully — capitulated, agreeing to: (1) pay Cloudflare $225,000, (2) grant Cloudflare a royalty-free license to Sable’s entire patent portfolio, and (3) dedicate all of Sable’s patents to the public.
With the fight against Sable ended, we announced the Conclusion of the Case under the Project Jengo Sable Rules. Now that the Grace Period has passed, we are pleased to announce the final winners of Project Jengo for the Sable case!
Read on for background on the case, details on the Project Jengo final winners, and other patent troll-related updates.
The Sable win
For anyone unfamiliar with the Sable case, the story can be traced back all the way to 2006, when patent troll Sable bought patents from a company going out of business. In 2021, fifteen years after buying the patents, Sable filed suit asserting these patents against a huge swath of companies: Cloudflare, Cisco, Fortinet, Check Point, SonicWall, Juniper Networks, and others. Sable knew that, no matter how weak its case, companies were likely to pay it just to avoid the considerable cost and trouble of litigating.
Cloudflare doesn’t pay trolls for meritless patent claims. Rather than paying off Sable to make the suit go away, we aggressively litigated the case, knocking out nearly 100 claims spanning 4 patents. By the time we got to trial, just a single claim was left.
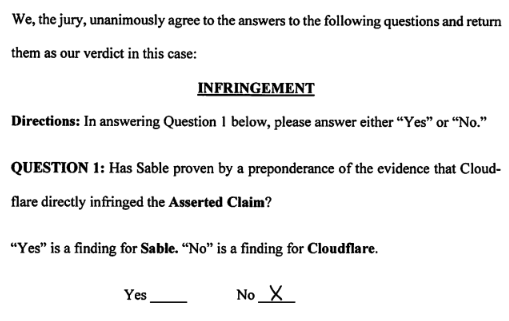
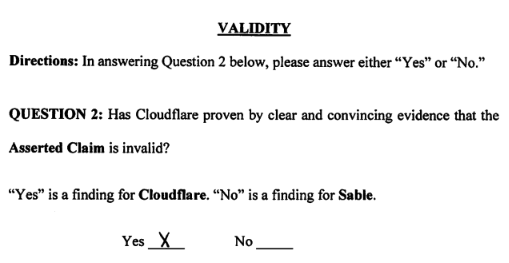
At trial, the jury’s verdict was decisive. After just 2 hours of deliberating, the jury found that Cloudflare didn’t infringe the remaining live claim (claim 25 of the ’919 patent). The jury then went on to also find that claim 25 was invalid in the first place.
In fact, Cloudflare’s victory was so complete that Sable didn’t bother appealing. Instead, Sable agreed to pay Cloudflare $225,000. In other words, not only did Sable miss out on its payday, it had to pay up for its failed litigation.
Even better, Sable granted Cloudflare a royalty-free license to its entire patent portfolio and dedicated all of its patents to the public, meaning Sable can no longer use these patents to profit off of frivolous lawsuits. This case, and Cloudflare’s aggressive defense, put Sable out of the patent troll business for good.
Announcing the final Project Jengo winners
With the Sable litigation resolved, it’s time to close out the Project Jengo contest!
Project Jengo is our prior art bounty program. It plays a fundamental role in our battle against patent trolls, helping us crowdsource key evidence that the trolls’ patents are invalid.
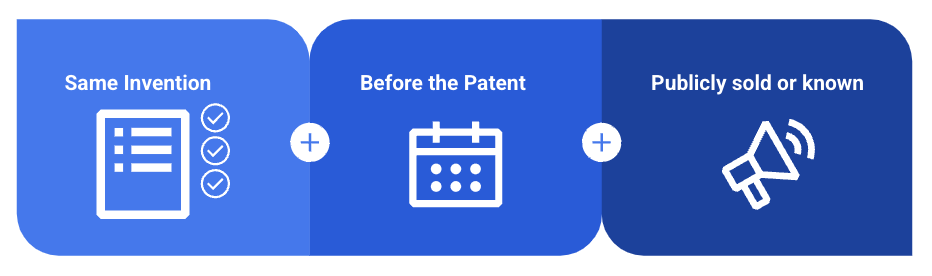
Prior art = instances of the inventions being claimed in the patents already being used or made public before the patent application was filed, meaning the patent is invalid.
Project Jengo began in 2017 when Cloudflare was sued by prolific patent troll Blackbird. We put out a call, offering cash rewards not just for prior art to invalidate the patents asserted against us in the lawsuit, but against any Blackbird patents. We received hundreds of submissions, more than half of which were related to patents that weren’t asserted against Cloudflare. That meant Project Jengo was a threat to Blackbird’s entire portfolio — far more than Blackbird bargained for when it first sued us. After several years of litigation, the program helped us soundly defeat Blackbird in court and put it out of business.
When Sable filed its suit in 2021, we revived Project Jengo for this next round in the fight against patent trolls. Cloudflare committed $100,000 to the Sable prior art search. Winners were announced after each of eight submission periods in blog posts here: Chapter 1, Chapter 2, Chapter 3, Chapters 4-6, and Chapters 7-8. Now, we’re ready to announce the Final Awards based on all of the submissions over the case’s journey. These Final Awards winners will collectively receive $30,000!
Jean-Pierre Le Rouzic: Cloudflare user, 12-time patent grantee, and our Chapter Two winner
Jean-Pierre received an additional $10,000 as a final winner for his contributions to the Sable round of Project Jengo!
As detailed in the blog post announcing Jean-Pierre’s chapter two victory, he is a retired telecommunications R&D engineer living in Rennes, France. Since retiring, he has been using Cloudflare for his blog.
After seeing Project Jengo on Hacker News, he decided to join in. He was particularly motivated because of the similar trends he sees within the pharmaceutical industry, of intellectual property (IP) profiteering displacing innovative R&D efforts. He explained:
The challenge faced by Cloudflare is close to my heart. … Cloudflare is facing an entity which is unreasonably stretching the meaning of their patent claims.
Jean-Pierre applied his patent expertise (he wrote 12 patents related to online authentication and identity management in the 2000s) to the Sable case. He followed a methodical process, preparing “two conceptual trees, one started from Sable patents and expanded with possible prior arts, and the other” from the asserted claims. Jean-Pierre ultimately prepared a 24-page submission, including a meticulously detailed claim chart, identifying prior art challenging the ’431 patent asserted against Cloudflare (titled “Micro-Flow Management” and concerning Internet switching technology for network service providers). See our prior post here for a detailed walk-through of his findings.
George J.: engineer, patent attorney, and our Chapter Seven winner
Like Jean-Pierre, George J. won an additional $10,000 for his submission during chapter seven!
George is an electrical engineer and patent attorney who is actively engaged in the IP community. He found out about Project Jengo on the legal site Law360. With a knack for prior art searches and claim charts, he decided to apply his professional background to the Sable challenge.
George’s submissions to Project Jengo included three prior art references for the ’431 patent. He also found that one of those three overlapped with the inventions in the ’919 patent (titled “Micro-Flow Label Switching”), the patent ultimately contested at trial. George provided 39 pages of detailed charts comparing the prior art he found against the Sable patents.
Peter S. and Jatin: our Chapter Four and Eight winners
Peter S. and Jatin have each been awarded $5,000 more for their submissions!
Peter S. is unique among this group of winners in lacking a technical/patent background. But when he saw Project Jengo on Cloudflare’s website, that didn’t stop him from deciding to take a stab at it. We’re glad he did! As we described in our prior post about Peter’s submission, the ʼ593 patent is the Sable patent concerning the detection of “bad” flows. Peter’s prior art reference developed the same thing five years earlier: “This thesis studies a means of using such mechanisms to identify nonadaptive [what Sable calls ‘bad’] network flows, and proposes a protocol to push this information, along with penalization responsibility, towards the flows’ sources.” Since Yang’s work predates the ’593 patent’s alleged new solutions by years, this was a great find.
Jatin, a computer science analyst who also discovered Project Jengo while reading Cloudflare’s blog, submitted two pieces of prior art. As we noted in the Chapter Eight post, they were particularly good references for Sable’s ’919 patent (the one patent that remained contested at trial).
In other troll-related news…
And there’s more! On the heels of the Sable litigation coming to a close, another troll filed but promptly abandoned its case against Cloudflare after realizing what it would have been up against.
Patent troll Touchpoint Projections Innovations sued Cloudflare in May 2024. Cloudflare was clear from the start that we would not back down. Several months later, when the case was still in its early stages, we published our blog post about Sable’s total capitulation — paying Cloudflare and getting out of the patent troll game.
Just two weeks later, Touchpoint voluntarily dismissed the case with prejudice. The “with prejudice” language means it’s final, and that the case can’t restart at any point in the future. In other words, Touchpoint threw in the towel before things had really gotten started.
Sure, the timing could be coincidental. But we have a hunch that when Touchpoint realized what they’d be up against, they took a hard look at their case, and decided it just wasn’t worth it.
We’ve seen this pattern before. Back in 2022, PacSec3 LLC accused Cloudflare of patent infringement. But after we made clear our intention to fight back, PacSec3 called it quits, dismissing its case.
Cloudflare’s trial victories and Project Jengo are sending a clear message to patent trolls. We’re not afraid of a fight! We hope other trolls take note and find other, more productive, avenues for their efforts.
Starting today, you can get more granular visibility of geographic location information for AWS Regions and AWS Availability Zones (AZs). This detailed information will help you choose the Regions and AZs that align with your regulatory, compliance, and operational requirements.
We continue to expand the AWS global infrastructure to meet your business requirements and now have 114 AZs across 36 Regions. We have announced plans to add 12 more AZs and four Regions in New Zealand, Kingdom of Saudi Arabia, Taiwan, and the AWS European Sovereign Cloud.
One of the things we’ve learned from our customers is the need to have more visibility into the specific location of infrastructure within an AWS Region. This is important for customers in highly regulated industries such as the financial industry or gaming, where there are specific requirements for the physical placement of infrastructure. For example, FanDuel, a leading sports gaming company based in the U.S., is scaling into new markets across the U.S. and Canada. They are taking advantage of the improved geographic transparency to make more informed decisions and ensure they’re meeting data residency requirements as they scale their business quickly.
Geographies for AWS Regions To find the geographic information for your Region, you can visit the AWS Global Infrastructure Regions and Availability Zones page. Once you navigate to this page, you can choose any tab on the map and scroll to the bottom to review the geographic information for each Region. See the following image for an example showing the North America Regions. As would be expected, the infrastructure for the US West (Oregon) Region is located in the United States of America, and the Canada (Central) Region is located in Canada.
Geographies for Availability Zones To find the specific geographic information for an AZ, you can visit the AWS Regions and Availability Zones page in AWS Documentation. Choose the Region you’re interested in and you’ll find a table showing you the geography for that Region. As you see in the following screenshot, the infrastructure of the AZ with AZ ID use1-az1 is located in Virginia, United States of America.
Stay tuned We will update these pages to reflect new geographic information as we continue to grow our AWS Global infrastructure footprint and add more AWS Regions and AZs.
(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)
Resilience has always been a top priority for customers running mission-critical Apache Kafka applications. Amazon Managed Streaming for Apache Kafka (Amazon MSK) is deployed across multiple Availability Zones and provides resilience within an AWS Region. However, mission-critical Kafka deployments require cross-Region resilience to minimize downtime during service impairment in a Region. With Amazon MSK Replicator, you can build multi-Region resilient streaming applications to provide business continuity, share data with partners, aggregate data from multiple clusters for analytics, and serve global clients with reduced latency. This post explains how to use MSK Replicator for cross-cluster data replication and details the failover and failback processes while keeping the same topic name across Regions.
MSK Replicator overview
Amazon MSK offers two cluster types: Provisioned and Serverless. Provisioned cluster supports two broker types: Standard and Express. With the introduction of Amazon MSK Express brokers, you can now deploy MSK clusters that significantly reduce recovery time by up to 90% while delivering consistent performance. Express brokers provide up to 3 times the throughput per broker and scale up to 20 times faster compared to Standard brokers running Kafka. MSK Replicator works with both broker types in Provisioned clusters and along with Serverless clusters.
MSK Replicator supports an identical topic name configuration, enabling seamless topic name retention during both active-active or active-passive replication. This avoids the risk of infinite replication loops commonly associated with third-party or open source replication tools. When deploying an active-passive cluster architecture for regional resilience, where one cluster handles live traffic and the other acts as a standby, an identical topic configuration simplifies the failover process. Applications can transition to the standby cluster without reconfiguration because topic names remain consistent across the source and target clusters.
To set up an active-passive deployment, you have to enable multi-VPC connectivity for the MSK cluster in the primary Region and deploy an MSK Replicator in the secondary Region. The replicator will consume data from the primary Region’s MSK cluster and asynchronously replicate it to the secondary Region. You connect the clients initially to the primary cluster but fail over the clients to the secondary cluster in the case of primary Region impairment. When the primary Region recovers, you deploy a new MSK Replicator to replicate data back from the secondary cluster to the primary. You need to stop the client applications in the secondary Region and restart them in the primary Region.
Because replication with MSK Replicator is asynchronous, there is a possibility of duplicate data in the secondary cluster. During a failover, consumers might reprocess some messages from Kafka topics. To address this, deduplication should occur on the consumer side, such as by using an idempotent downstream system like a database.
In the next sections, we demonstrate how to deploy MSK Replicator in an active-passive architecture with identical topic names. We provide a step-by-step guide for failing over to the secondary Region during a primary Region impairment and failing back when the primary Region recovers. For an active-active setup, refer to Create an active-active setup using MSK Replicator.
Solution overview
In this setup, we deploy a primary MSK Provisioned cluster with Express brokers in the us-east-1 Region. To provide cross-Region resilience for Amazon MSK, we establish a secondary MSK cluster with Express brokers in the us-east-2 Region and replicate topics from the primary MSK cluster to the secondary cluster using MSK Replicator. This configuration provides high resilience within each Region by using Express brokers, and cross-Region resilience is achieved through an active-passive architecture, with replication managed by MSK Replicator.
The following diagram illustrates the solution architecture.
The primary Region MSK cluster handles client requests. In the event of a failure to communicate to MSK cluster due to primary region impairment, you need to fail over the clients to the secondary MSK cluster. The producer writes to the customer topic in the primary MSK cluster, and the consumer with the group ID msk-consumer reads from the same topic. As part of the active-passive setup, we configure MSK Replicator to use identical topic names, making sure that the customer topic remains consistent across both clusters without requiring changes from the clients. The entire setup is deployed within a single AWS account.
In the next sections, we describe how to set up a multi-Region resilient MSK cluster using MSK Replicator and also show the failover and failback strategy.
This will create the virtual private cloud (VPC), subnets, and the MSK Provisioned cluster with Express brokers within the VPC configured with AWS Identity and Access Management (IAM) authentication in each Region. It will also create a Kafka client Amazon Elastic Compute Cloud (Amazon EC2) instance, where we can use the Kafka command line to create and view a Kafka topic and produce and consume messages to and from the topic.
Configure multi-VPC connectivity in the primary MSK cluster
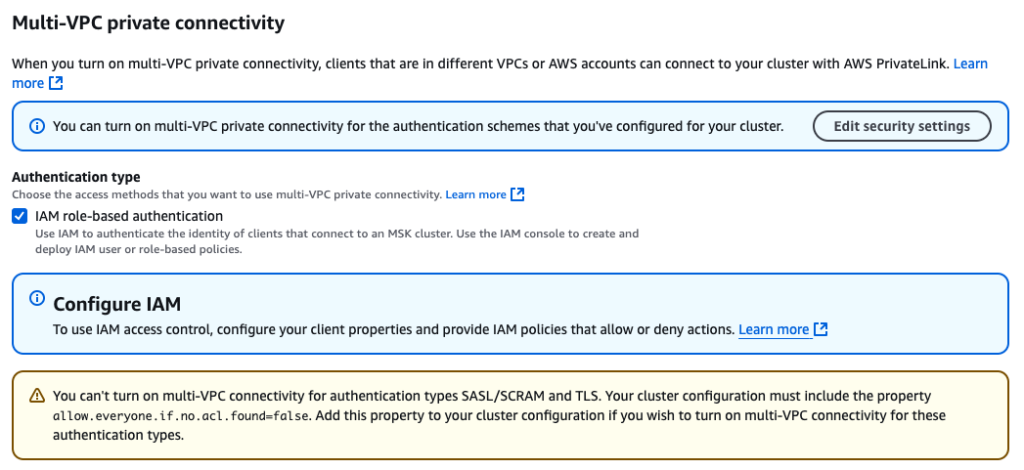
After the clusters are deployed, you need to enable the multi-VPC connectivity in the primary MSK cluster deployed in us-east-1. This will allow MSK Replicator to connect to the primary MSK cluster using multi-VPC connectivity (powered by AWS PrivateLink). Multi-VPC connectivity is only required for cross-Region replication. For same-Region replication, MSK Replicator uses an IAM policy to connect to the primary MSK cluster.
MSK Replicator uses IAM authentication only to connect to both primary and secondary MSK clusters. Therefore, although other Kafka clients can still continue to use SASL/SCRAM or mTLS authentication, for MSK Replicator to work, IAM authentication has to be enabled.
To enable multi-VPC connectivity, complete the following steps:
On the Amazon MSK console, navigate to the MSK cluster.
On the Properties tab, under Network settings, choose Turn on multi-VPC connectivity on the Edit dropdown menu.
For Authentication type, select IAM role-based authentication.
Choose Turn on selection.
Enabling multi-VPC connectivity is a one-time setup and it can take approximately 30–45 minutes depending on the number of brokers. After this is enabled, you need to provide the MSK cluster resource policy to allow MSK Replicator to talk to the primary cluster.
Under Security settings¸ choose Edit cluster policy.
Select Include Kafka service principal.
Now that the cluster is enabled to receive requests from MSK Replicator using PrivateLink, we need to set up the replicator.
Create a MSK Replicator
Complete the following steps to create an MSK Replicator:
In the secondary Region (us-east-2), open the Amazon MSK console.
Choose Replicators in the navigation pane.
Choose Create replicator.
Enter a name and optional description.
In the Source cluster section, provide the following information:
For Cluster region, choose us-east-1.
For MSK cluster, enter the Amazon Resource Name (ARN) for the primary MSK cluster.
For cross-Region setup, the primary cluster will appear disabled if the multi-VPC connectivity is not enabled and the cluster resource policy is not configured in the primary MSK cluster. After you choose the primary cluster, it automatically selects the subnets associated with primary cluster. Security groups are not required because the primary cluster’s access is governed by the cluster resource policy.
Next, you select the target cluster. The target cluster Region is defaulted to the Region where the MSK Replicator is created. In this case, it’s us-east-2.
In the Target cluster section, provide the following information:
For MSK cluster, enter the ARN of the secondary MSK cluster. This will automatically select the cluster subnets and the security group associated with the secondary cluster.
For Security groups, choose any additional security groups.
Make sure that the security groups have outbound rules to allow traffic to your secondary cluster’s security groups. Also make sure that your secondary cluster’s security groups have inbound rules that accept traffic from the MSK Replicator security groups provided here.
Now let’s provide the MSK Replicator settings.
In the Replicator settings section, enter the following information:
For Topics to replicate, we keep the topics to replicate as a default value that replicates all topics from the primary to secondary cluster.
For Replication starting position, we choose Earliest, so that we can get all the events from the start of the source topics.
For Copy settings, select Keep the same topic names to configure the topic name in the secondary cluster as identical to the primary cluster.
This makes sure that the MSK clients don’t need to add a prefix to the topic names.
For this example, we keep the Consumer group replication setting as default and set Target compression type as None.
Also, MSK Replicator will automatically create the required IAM policies.
Choose Create to create the replicator.
The process takes around 15–20 minutes to deploy the replicator. After the MSK Replicator is running, this will be reflected in the status.
Configure the MSK client for the primary cluster
Complete the following steps to configure the MSK client:
On the Amazon EC2 console, navigate to the EC2 instance of the primary Region (us-east-1) and connect to the EC2 instance dr-test-primary-KafkaClientInstance1 using Session Manager, a capability of AWS Systems Manager.
After you have logged in, you need to configure the primary MSK cluster bootstrap address to create a topic and publish data to the cluster. You can get the bootstrap address for IAM authentication on the Amazon MSK console under View Client Information on the cluster details page.
Configure the bootstrap address with the following code:
sudo su - ec2-user

export BS_PRIMARY=<<MSK_BOOTSTRAP_ADDRESS>>
Configure the client configuration for IAM authentication to talk to the MSK cluster:
This will consume both the sample messages from the topic.
Press Ctrl+C to exit the console prompt.
Configure the MSK client for the secondary MSK cluster
Go to the EC2 cluster of the secondary Region us-east-2 and follow the previously mentioned steps to configure an MSK client. The only difference from the previous steps is that you should use the bootstrap address of the secondary MSK cluster as the environment variable. Configure the variable $BS_SECONDARY to configure the secondary Region MSK cluster bootstrap address.
Verify replication
After the client is configured to talk to the secondary MSK cluster using IAM authentication, list the topics in the cluster. Because the MSK Replicator is now running, the customer topic is replicated. To verify it, let’s see the list of topics in the cluster:
By default, MSK Replicator replicates the details of all the consumer groups. Because you used the default configuration, you can verify using the following command if the consumer group ID msk-consumer is also replicated to the secondary cluster:
Now that we have verified the topic is replicated, let’s understand the key metrics to monitor.
Monitor replication
Monitoring MSK Replicator is very important to make sure that replication of data is happening fast. This reduces the risk of data loss in case an unplanned failure occurs. Some important MSK Replicator metrics to monitor are ReplicationLatency, MessageLag, and ReplicatorThroughput. For a detailed list, see Monitor replication.
To understand how many bytes are processed by MSK Replicator, you should monitor the metric ReplicatorBytesInPerSec. This metric indicates the average number of bytes processed by the replicator per second. Data processed by MSK Replicator consists of all data MSK Replicator receives. This includes the data replicated to the target cluster and filtered by MSK Replicator. This metric is applicable if you use Keep same topic name in the MSK Replicator copy settings. During a failback scenario, MSK Replicator starts to read from the earliest offset and replicates records from the secondary back to the primary. Depending on the retention settings, some data might exist in the primary cluster. To prevent duplicates, MSK Replicator processes the data but automatically filters out duplicate data.
Fail over clients to the secondary MSK cluster
In the case of an unexpected event in the primary Region in which clients can’t connect to the primary MSK cluster or the clients are receiving unexpected produce and consume errors, this could be a sign that the primary MSK cluster is impacted. You may notice a sudden spike in replication latency. If the latency continues to rise, it could indicate a regional impairment in Amazon MSK. To verify this, you can check the AWS Health Dashboard, though there is a chance that status updates may be delayed. Once you identify signs of a regional impairment in Amazon MSK, you should prepare to fail over the clients to the secondary region.
For critical workloads we recommend not taking a dependency on control plane actions for failover. To mitigate this risk, you could implement a pilot light deployment, where essential components of the stack are kept running in a secondary region and scaled up when the primary region is impaired. Alternatively, for faster and smoother failover with minimal downtime, a hot standby approach is recommended. This involves pre-deploying the entire stack in a secondary region so that, in a disaster recovery scenario, the pre-deployed clients can be quickly activated in the secondary region.
Failover process
To perform the failover, you first need to stop the clients pointed to the primary MSK cluster. However, for the purpose of the demo, we are using console producer and consumers, so our clients are already stopped.
In a real failover scenario, using primary Region clients to communicate with the secondary Region MSK cluster is not recommended, as it breaches fault isolation boundaries and leads to increased latency. To simulate the failover using the preceding setup, let’s start a producer and consumer in the secondary Region (us-east-2). For this, run a console producer in the EC2 instance (dr-test-secondary-KafkaClientInstance1) of the secondary Region.
The following diagram illustrates this setup.
Complete the following steps to perform a failover:
Create a console producer using the following code:
This is the 3rd message to the topic.
This is the 4th message to the topic.
Now, let’s create a console consumer. It’s important to make sure the consumer group ID is exactly the same as the consumer attached to the primary MSK cluster. For this, we use the group.idmsk-consumer to read the messages from the customer topic. This simulates that we are bringing up the same consumer attached to the primary cluster.
Create a console consumer with the following code:
Although the consumer is configured to read all the data from the earliest offset, it only consumes the last two messages produced by the console producer. This is because MSK Replicator has replicated the consumer group details along with the offsets read by the consumer with the consumer group ID msk-consumer. The console consumer with the same group.id mimic the behaviour that the consumer is failed over to the secondary Amazon MSK cluster.
Fail back clients to the primary MSK cluster
Failing back clients to the primary MSK cluster is the common pattern in an active-passive scenario, when the service in the primary region has recovered. Before we fail back clients to the primary MSK cluster, it’s important to sync the primary MSK cluster with the secondary MSK cluster. For this, we need to deploy another MSK Replicator in the primary Region configured to read from the earliest offset from the secondary MSK cluster and write to the primary cluster with the same topic name. The MSK Replicator will copy the data from the secondary MSK cluster to the primary MSK cluster. Although the MSK Replicator is configured to start from the earliest offset, it will not duplicate the data already present in the primary MSK cluster. It will automatically filter out the existing messages and will only write back the new data produced in the secondary MSK cluster when the primary MSK cluster was down. The replication step from secondary to primary wouldn’t be required if you don’t have a business requirement of keeping the data same across both clusters.
After the MSK Replicator is up and running, monitor the MessageLag metric of MSK Replicator. This metric indicates how many messages are yet to be replicated from the secondary MSK cluster to the primary MSK cluster. The MessageLag metric should come down close to 0. Now you should stop the producers writing to the secondary MSK cluster and restart connecting to the primary MSK cluster. You should also allow the consumers to read data from the secondary MSK cluster until the MaxOffsetLag metric for the consumers is not 0. This makes sure that the consumers have already processed all the messages from the secondary MSK cluster. The MessageLag metric should be 0 by this time because no producer is producing records in the secondary cluster. MSK Replicator replicated all messages from the secondary cluster to the primary cluster. At this point, you should start the consumer with the same group.id in the primary Region. You can delete the MSK Replicator created to copy messages from the secondary to the primary cluster. Make sure that the previously existing MSK Replicator is in RUNNING status and successfully replicating messages from the primary to secondary. This can be confirmed by looking at the ReplicatorThroughput metric, which should be greater than 0.
Failback process
To simulate a failback, you first need to enable multi-VPC connectivity in the secondary MSK cluster (us-east-2) and add a cluster policy for the Kafka service principal like we did before.
Deploy the MSK Replicator in the primary Region (us-east-1) with the source MSK cluster pointed to us-east-2 and the target cluster pointed to us-east-1. Configure Replication starting position as Earliest and Copy settings as Keep the same topic names.
The following diagram illustrates this setup.
After the MSK Replicator is in RUNNING status, let’s verify there is no duplicate while replicating the data from the secondary to the primary MSK cluster.
Run a console consumer without the group.id in the EC2 instance (dr-test-primary-KafkaClientInstance1) of the primary Region (us-east-1):
This should show the four messages without any duplicates. Although in the consumer we specify to read from the earliest offset, MSK Replicator makes sure the duplicate data isn’t replicated back to the primary cluster from the secondary cluster.
This is a customer topic
This is the 2nd message to the topic.
This is the 3rd message to the topic.
This is the 4th message to the topic.
You can now point the clients to start producing to and consuming from the primary MSK cluster.
Clean up
At this point, you can tear down the MSK Replicator deployed in the primary Region.
Conclusion
This post explored how to enhance Kafka resilience by setting up a secondary MSK cluster in another Region and synchronizing it with the primary cluster using MSK Replicator. We demonstrated how to implement an active-passive disaster recovery strategy while maintaining consistent topic names across both clusters. We provided a step-by-step guide for configuring replication with identical topic names and detailed the processes for failover and failback. Additionally, we highlighted key metrics to monitor and outlined actions to provide efficient and continuous data replication.
Subham Rakshit is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them. Connect with him on LinkedIn.
Creating clear goals is inevitably part of any business strategy. You’ve likely heard of the acronym SMART—specific, measurable, actionable, realistic, and time-bound—when it comes to goal setting. As a business leader in information technology or a related business unit, you’re responsible for developing sound goals for business technology, data protection, and disaster recovery.
Two key metrics that feed into those strategies are your recovery time objective (RTO) and recovery point objective (RPO). Like all the other goals your business sets, the RTO and RPO should also be SMART goals.
So, how can you set meaningful RTO and RPO objectives for your business? And how can the cloud help you achieve or improve on those objectives? Today I’ll talk about how to smarten up these objectives to lead to better business continuity (BC) and a more effective disaster recovery (DR) plan.
The Essential Guide to Disaster Recovery Planning
Read more about how to build a disaster recovery plan for your organization.
Why do RTO and RPO matter?
RTO and RPO are two fundamental inputs to a comprehensive disaster recovery plan. They also very much guide how you’ll structure your backup strategy and engineer your backup architecture.
RTO is a business metric that states the maximum length of time a business can tolerate for recovery. It’s important to note the difference between recovery and restoration of data here. Restoring data is just one part of a recovery.
Recovery means systems are back up and running—fully functional—with users (employees, customers, etc.) able to utilize them in the same manner as before the data incident occurred.
RPO measures the maximum amount of data a company can afford to lose (or is willing to lose), measured in units of time. For instance, an RPO of 12 hours means that the company can accept the risk (financial risk, risk to the brand, etc.) of having lost 12 hours worth of data. So, if you run backups every 11 hours, you will be able to meet your RPO.
How to set RTO and RPO
Creating these objectives is a business decision—not an IT decision. If you’re an IT leader, your job is to work with your internal stakeholders to fully understand the business and the criticality of various applications and services in order to help define the RTO and RPO.
Put another way: The decision about what standard to meet is a shared responsibility. And those standards (recovery time, file durability, etc.) are the targets that IT and infrastructure providers teams must meet.
RTO and RPO may be different from one system to another. Some applications are more important than others.
Keep in mind that it’s likely that department heads will all say their services are the most important to immediately recover. But if everything is deemed critical, then nothing is.
Discuss how data loss and time to recovery impact the business in quantifiable details—revenue lost, number of customers affected, etc.—in order to truly prioritize systems and set appropriate RTOs and RPOs.
Making your RTOs and RPOs SMART
Remember that your objectives should be SMART:
Specific: Think through how granular your RTOs and RPOs should be. In addition to different RTOs and RPOs per application, you may also need different RTOs and RPOs per scenario. For example, the RTO for a ransomware attack is much different than that for hardware failure.
Measurable: One good way of measuring the efficacy of your RTOs and RPOs is by conducting DR testing. Run fire drills and conduct tabletop exercises. Practice restoring data. These inputs will help you understand if your objectives are meaningful and obtainable.
Actionable: Document your RTO and RPO in your DR plans and ensure they align with any business continuity risk management plans or goals around maximum allowable risk tolerance. You may also want to document the assumptions and inputs that formed the RTO and RPO. For instance, how much revenue is lost when a given system is down? Explain how that factor drives your RTO.
Realistic: Don’t let your stakeholders set unachievable objectives. If there is an ask for a very low RTO and/or RPO, help your stakeholder understand exactly what it will take—and how much it will cost—to implement that objective.
Time-bound: The RTO can be defined in seconds up to weeks. The shorter the RTO, the more expensive the investment will be to meet it.
Remember that you’re always balancing RTO and RPO against an unachievable “perfect” state. For instance, you would likely need multiple failover hot sites with replicated data to meet an RTO of seconds of downtime.
RTO is a forward-looking measurement; RPO is a backward-looking measurement that essentially represents the frequency of your backups.
A short RPO means more recent backup data is needed, and, yes, that also means greater investment. RPOs measured in seconds may require high-speed backup technology like continuous replication.
How to discuss RTO and RPO with business leaders
Discussing technical concepts with internal stakeholders can be challenging. To guide the objective-setting discussion with stakeholders, use the following questions as a guide:
Where and how do you store data?
How often does your data change?
What would a minute of downtime cost your department, in terms of revenue, risk, loss of productivity, impact to customers, etc.?
What are the compliance or industry requirements for maintaining sensitive data?
Do you have a way of manually transacting business if service is down?
Your IT department may already be well aware of many of these goals, but it’s good to do a fresh and full inventory of data and data management procedures. For example, even with the rise of shared drives, many employees still save important data locally. Or, there may be business-critical data being saved in services like Microsoft 365 or Kubernetes—and those services are often not adequately backed up.
How do RTO and RPO affect backup strategy?
Your RPO is often more directly related to backup strategy, although RTO certainly informs backup strategy. If you need a very low RPO (i.e., the business can tolerate very little data loss), you must plan to run backups more frequently. This ensures you always have very recent data to recover.
RTO, however, relates more to systems and infrastructure—again, because the objective is about recovery and not just restoring data. RTO will drive investment decisions around backup and DR architecture.
Your backup strategy or tech stack should not dictate either your RTO or your RPO.
First, you should define your RTO and RPO, and then you must determine if changes in backup policy are needed or if you need to update any backup systems in order to reach desired RTOs and RPOs.
Your RTO will drive decisions around backup and DR infrastructure; your RPO will drive decisions around frequency of backup and type of backup.
How does the cloud help companies meet RTO and RPO goals?
Using a public cloud for backup and archive can help you achieve your desired RTO and/or RPO. An obvious example is using cloud to replace LTO tape backup. Tape backup has some of the worst (maybe the worst) RTOs and RPOs. It takes an extraordinarily long time to recover from tape, and backups are likely not as frequent as they should be because tape is often not properly maintained. Migrating your tape backups to a public cloud like Backblaze B2 Cloud Storage is still cost-effective and it will drastically improve RTO and RPO.
If you’re using a hyperscaler like AWS, you may have had to cut back on frequency of backup or needed retention periods due to exorbitant fees. Shifting your backups to Backblaze B2 can help you achieve your goals: Backblaze B2 is one-fifth the cost of AWS S3, you can afford to run and save more frequent backups, thus lowering your overall RPO.
Replication is another technology that can help reduce RTOs. Many enterprise businesses will already have a failover site, but keeping an extra copy of your data in the cloud ensures you can still meet your desired RTO in the case of a DR site or production facility takeout. This is exactly what brought SaaS platform Centerbase to Backblaze.
More commonly, if it’s inordinately expensive to own your own DR site, you can store your backups in Backblaze B2 and utilize Cloud Replication for added redundancy.
RTO and RPO and your business
Ultimately, you should frame your RTO and RPO in terms of business impact. Then, reverse engineer your backup and DR infrastructure to support those objectives. Next, identify the storage systems for your data based on its business criticality and desired RTO and RPO.
Depending on your business goals, you’ll likely use cloud storage services, on-premises storage, or some combination of the two. Regardless of the type of business you run, demonstrating that you have an airtight DR plan with SMART RTO and RPO goals will instill confidence in your business partners, help with cyber insurance eligibility, and shore up your organization’s ability to withstand data disasters.
Boudhayan Bhattcharya has posted a lengthy article
about the announcement
that the Freedesktop project is dropping OpenH264 from the Freedesktop SDK for Flatpak
applications and runtimes.
Some Flatpak applications that depend on the Freedesktop runtime
version 23.08 will lose H.264 playback support starting with the
release scheduled for April, unless application developers replace it
with the ffmpeg-full extension. The 24.08 runtime is
unaffected, and future releases will include a new codecs-extra extension to replace OpenH264 that includes FFmpeg with support for a number of
patented codecs.
Considering all things, I think and hope we made the correct decision
and hopefully the new org.freedesktop.Platform.codecs-extra works
out. libx264, libx265 and others are built from source and there are
no binaries or extra-data involved. So we should theoretically be able
to patch and fix any issues that come up in the future.
Apart from all this, I’m slightly worried at the prospects of legal
issues cropping up with this setup and also that the new extension
contains “too much”, but we will have to see where things flow.
On March 24, 2025, Kubernetes disclosed 5 new vulnerabilities affecting the Ingress NGINX Controller for Kubernetes. Successful exploitation could allow attackers access to all secrets stored across all namespaces in the Kubernetes cluster, which could result in cluster takeover.
CVE-2025-1974 (9.8 Critical): RCE escalation. An unauthenticated attacker with access to the pod network can achieve arbitrary code execution in the context of the ingress-nginx controller. This can lead to disclosure of Secrets accessible to the controller. (In the default installation, the controller can access all Secrets cluster-wide.)
CVE-2025-24514(8.8 High): Configuration injection via unsanitized auth-url annotation. In ingress-nginx, the `auth-url` Ingress annotation can be used to inject configuration into nginx. This can lead to arbitrary code execution in the context of the ingress-nginx controller, and disclosure of Secrets accessible to the controller.
CVE-2025-1097 (8.8 High): Configuration injection via unsanitized auth-tls-match-cn annotation. The `auth-tls-match-cn` Ingress annotation can be used to inject configuration into nginx. This can lead to arbitrary code execution in the context of the ingress-nginx controller, and disclosure of Secrets accessible to the controller.
CVE-2025-1098 (8.8 High): Configuration injection via unsanitized mirror annotations. The `mirror-target` and `mirror-host` Ingress annotations can be used to inject arbitrary configuration into nginx. This can lead to arbitrary code execution in the context of the ingress-nginx controller, and disclosure of Secrets accessible to the controller.
CVE-2025-24513 (4.8 Medium): Auth secret file path traversal vulnerability. Attacker-provided data is included in a filename by the ingress-nginx Admission Controller feature, resulting in directory traversal within the container. This could result in denial of service, or when combined with other vulnerabilities, limited disclosure of Secret objects from the cluster.
Of the 5 vulnerabilities disclosed, any one of the injection vulnerabilities (CVE-2025-24514, CVE-2025-1097, CVE-2025-1098) may be chained with CVE-2025-1974 to achieve unauthenticated RCE on the Kubernetes pod that is running a vulnerable Ingress NGINX Controller. Achieving RCE could allow an attacker to take over a Kubernetes cluster. As of March 25, 2025, none of the above CVEs is known to be exploited in the wild.
Ingress is a Kubernetes feature to route HTTP(S) traffic into a Kubernetes cluster. An Ingress Controller is an application responsible for performing the routing. While there are many Ingress Controllers available, the vulnerabilities disclosed on March 24 are specific to the Ingress NGINX Controller, which is an Ingress Controller based upon NGINX.
The original finders of all five vulnerabilities, Wiz, noted that 43% of cloud environments are vulnerable to the issues disclosed, and that they have identified 6,500 clusters with publicly exposed Ingress NGINX Controllers.
As of March 25, 2025 (14:00 pm GMT), there is now one known publicly available RCE exploit for CVE-2025-1974 (here). This exploit is unverified, but based on our understanding of the vulnerability, it appears viable.
Mitigation guidance
All 5 vulnerabilities are reported to affect the following versions of Ingress NGINX Controller:
Versions <= 1.11.4
Version 1.12.0
Notably, the Wiz advisory says that CVE-2025-24514 does not affect version 1.12.0, but the vendor indicates that the issue does affect 1.12.0.
Customers who use the Ingress NGINX Controller for Kubernetes are advised to update to the following versions immediately:
Version 1.11.5
Version 1.12.1
Rapid7 customers
With the latest Kubernetes Cluster Scanner (expected to be available Wednesday, March 26), InsightCloudSec customers will have the ability to discover Kubernetes workloads that have this vulnerability in their cluster. The discovery will be shown via the insights pack with a new insight called Publicly exposed vulnerable Ingress NGINX Admission. The insight will also include the remediation steps needed in order to resolve this vulnerability.
Rapid7 is warning customers of notable vulnerabilities in Next.js, a React framework for building web applications, and CrushFTP, a file transfer technology that has previously been targeted by adversaries.
CVE-2025-29927 is a critical improper authorization vulnerability in Next.js middleware that could (theoretically) allow an attacker to bypass authorization checks in a Next.js application, if the authorization check occurs in middleware.
No CVE has been assigned (as of March 25, 2025) to an unauthenticated HTTP(S) port access vulnerability in CrushFTP file transfer software
Neither of the above vulnerabilities is known to have been exploited in the wild as of Tuesday, March 25, 2025. CrushFTP has previously been exploited in the wild for adversary access to (and exfiltration of) sensitive data.
CrushFTP unauthenticated HTTP(S) port access vulnerability (no CVE)
On Friday, March 21, 2025, file transfer software maker CrushFTP disclosed a new vulnerability to customers via email:
Note: While the email image above indicates only CrushFTP v11 is affected by the still-CVE-less (as of March 25) unauthenticated port access vulnerability, the extremely sparse vendor advisory indicates that both CrushFTP v10 and v11 are affected. According to the vendor, the issue is not exploitable if customers have the DMZ function of CrushFTP in place.
Mitigation guidance: File transfer technologies are high-value targets for ransomware and other adversaries looking to quickly gain access to and exfiltrate sensitive data.Per the email sent to CrushFTP customers on Friday, March 21, the vulnerability is fixed in CrushFTP v11.3.1 (and later). Customers should update immediately, without waiting for a regular patch cycle to occur.
Next.js CVE-2025-29927
CVE-2025-29927 stems from logic associated with how middleware is handled by the application — specifically, an attacker can provide a header in any request to bypass application middleware. Application middleware can perform any number of tasks, and it can stack so that multiple layers of middleware can be configured, with each able to modify the request/response passed to it. Common use cases of middleware include authentication/authorization, CSP validation, URL rewriting/redirection etc.
As the vulnerability affects an application framework, and the application middleware configuration can vary greatly, so too does the potential impact of exploiting the vulnerability. Based on Rapid7’s analysis, there is no ‘one-size-fits-all’ determination of risk/impact for CVE-2025-29927 (which is a common scenario for framework and library vulns). The most severe potential impact likely comes in the form of authentication bypass, but would still be highly application-dependent — the impact of bypassing authentication for a hobbyist “To do list” application is very different from theoretically bypassing authentication in an enterprise application utilising Next.js.
Organizations should consider whether their applications are relying solely on the middleware for authentication. It may be that the application uses middleware, but is just acting as a front end to back-end APIs that are dealing with server-side authentication logic. Bypassing the front-end Next.js middleware would not affect the back end’s ability to authenticate users.
As an example of how a more measured view can change the outlook, a Red Hat advisory for CVE-2025-29927 originally listed two products as affected: Red Hat Trusted Artifact Signer and Streams for Apache Kafka 2. Now these have been removed and classified as “Not affected,” presumably following further review. The advisory was updated with the following: “Red Hat Trusted Artifact Signer and Streams for Apache Kafka 2 are not affected by this vulnerability as they do not use Next.js for any authorization functionality.”
Mitigation guidance: Per the Next.js advisory, CVE-2025-29927 affects the following versions of Next.js:
>= 13.0.0, < 13.5.9 (fixed in 13.5.9)
>= 14.0.0, < 14.2.25 (fixed in 14.2.25)
>= 15.0.0, < 15.2.3 (fixed in 15.2.3)
>= 11.1.4, < 12.3.5 (fixed in 12.3.5)
Rapid7 customers
InsightVM and Nexpose customers who run CrushFTP on Linux can assess their exposure to the no-CVE unauthenticated HTTP(S) port access issue with a vulnerability check available in the Friday, March 21 content release.
Our InsightVM coverage team is assessing the feasibility of adding a vulnerability check for Next.js CVE-2025-29927. We will update this blog with further information no later than 6 AM ET on Wednesday, March 26, 2025.
It feels like almost everyone building AI applications and agents is talking about the Model Context Protocol (MCP), as well as building MCP servers that you install and run locally on your own computer.
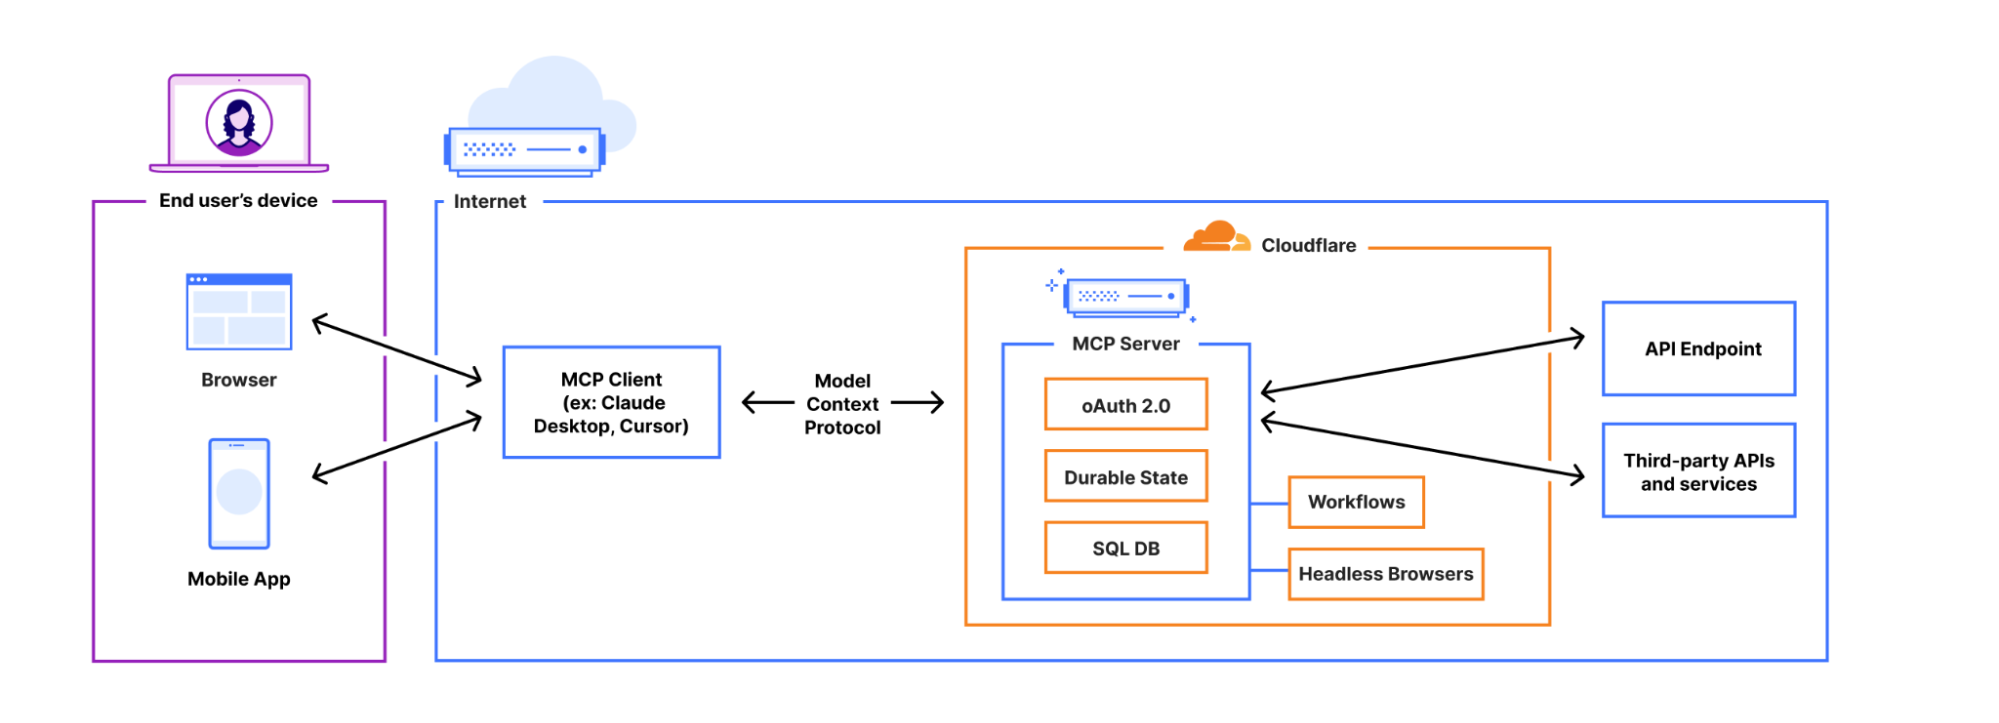
You can now build and deploy remote MCP servers to Cloudflare. We’ve added four things to Cloudflare that handle the hard parts of building remote MCP servers for you:
Unlike the local MCP servers you may have previously used, remote MCP servers are accessible on the Internet. People simply sign in and grant permissions to MCP clients using familiar authorization flows. We think this is going to be a massive deal — connecting coding agents to MCP servers has blown developers’ minds over the past few months, and remote MCP servers have the same potential to open up similar new ways of working with LLMs and agents to a much wider audience, including more everyday consumer use cases.
From local to remote — bringing MCP to the masses
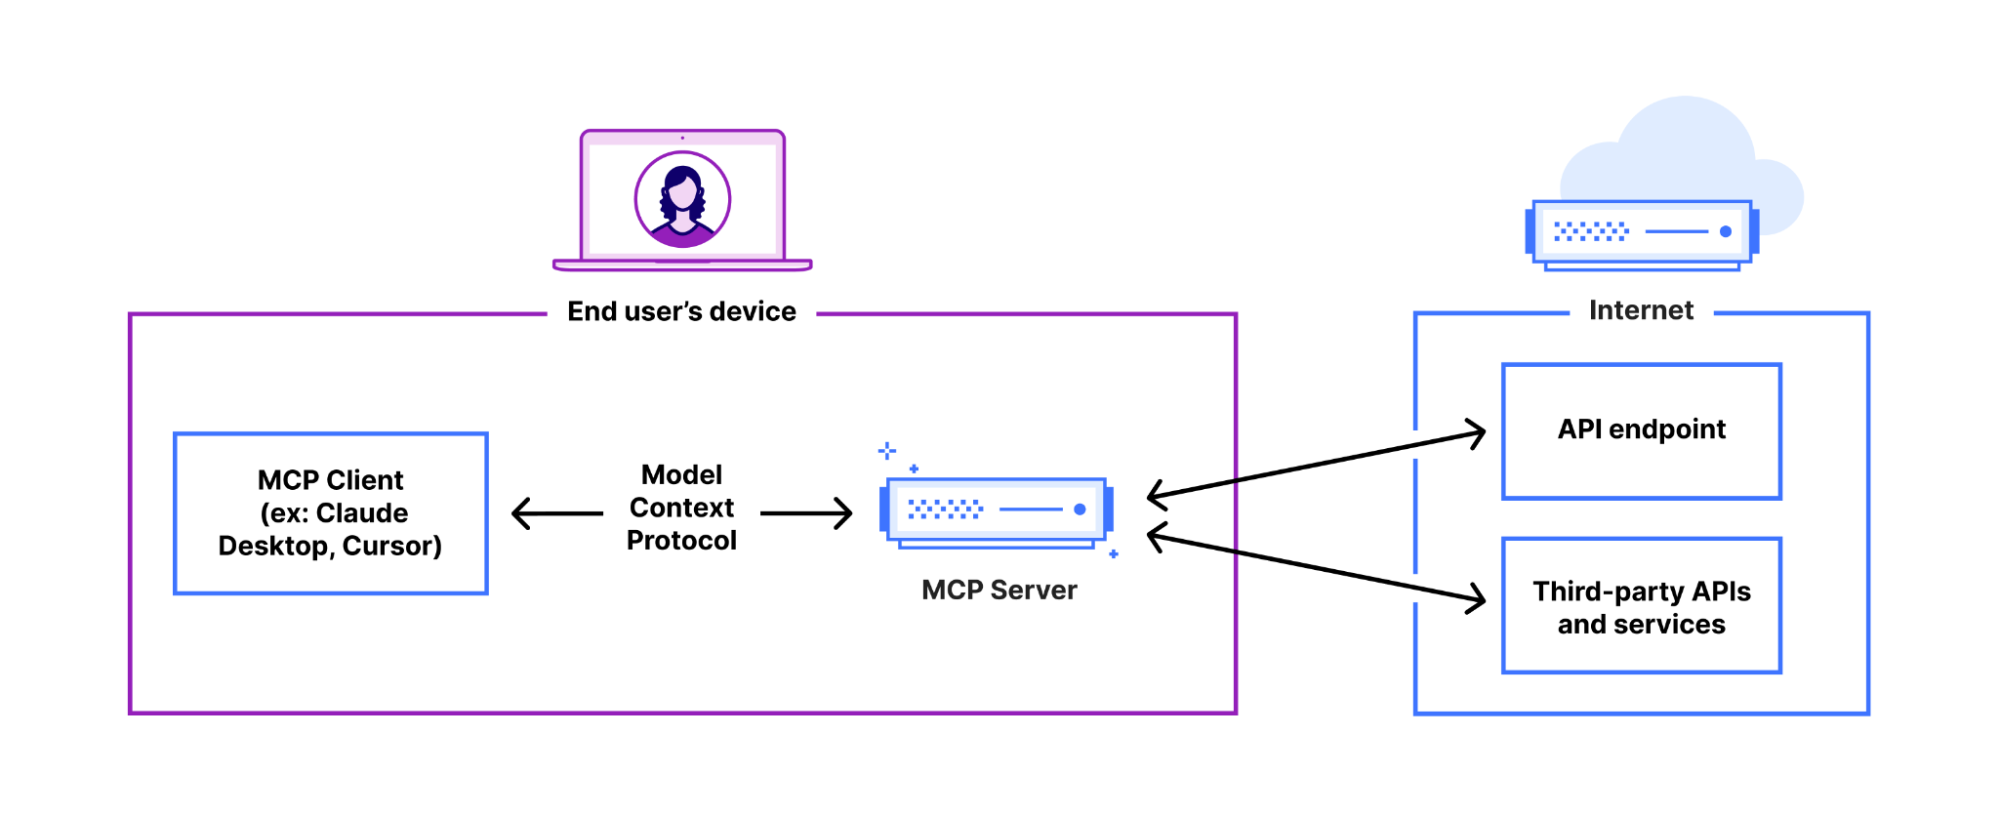
MCP is quickly becoming the common protocol that enables LLMs to go beyond inference and RAG, and take actions that require access beyond the AI application itself (like sending an email, deploying a code change, publishing blog posts, you name it). It enables AI agents (MCP clients) to access tools and resources from external services (MCP servers).
To date, MCP has been limited to running locally on your own machine — if you want to access a tool on the web using MCP, it’s up to you to set up the server locally. You haven’t been able to use MCP from web-based interfaces or mobile apps, and there hasn’t been a way to let people authenticate and grant the MCP client permission. Effectively, MCP servers haven’t yet been brought online.
Support for remote MCP connections changes this. It creates the opportunity to reach a wider audience of Internet users who aren’t going to install and run MCP servers locally for use with desktop apps. Remote MCP support is like the transition from desktop software to web-based software. People expect to continue tasks across devices and to login and have things just work. Local MCP is great for developers, but remote MCP connections are the missing piece to reach everyone on the Internet.
Making authentication and authorization just work with MCP
Beyond just changing the transport layer — from stdio to streamable HTTP — when you build a remote MCP server that uses information from the end user’s account, you need authentication and authorization. You need a way to allow users to login and prove who they are (authentication) and a way for users to control what the AI agent will be able to access when using a service (authorization).
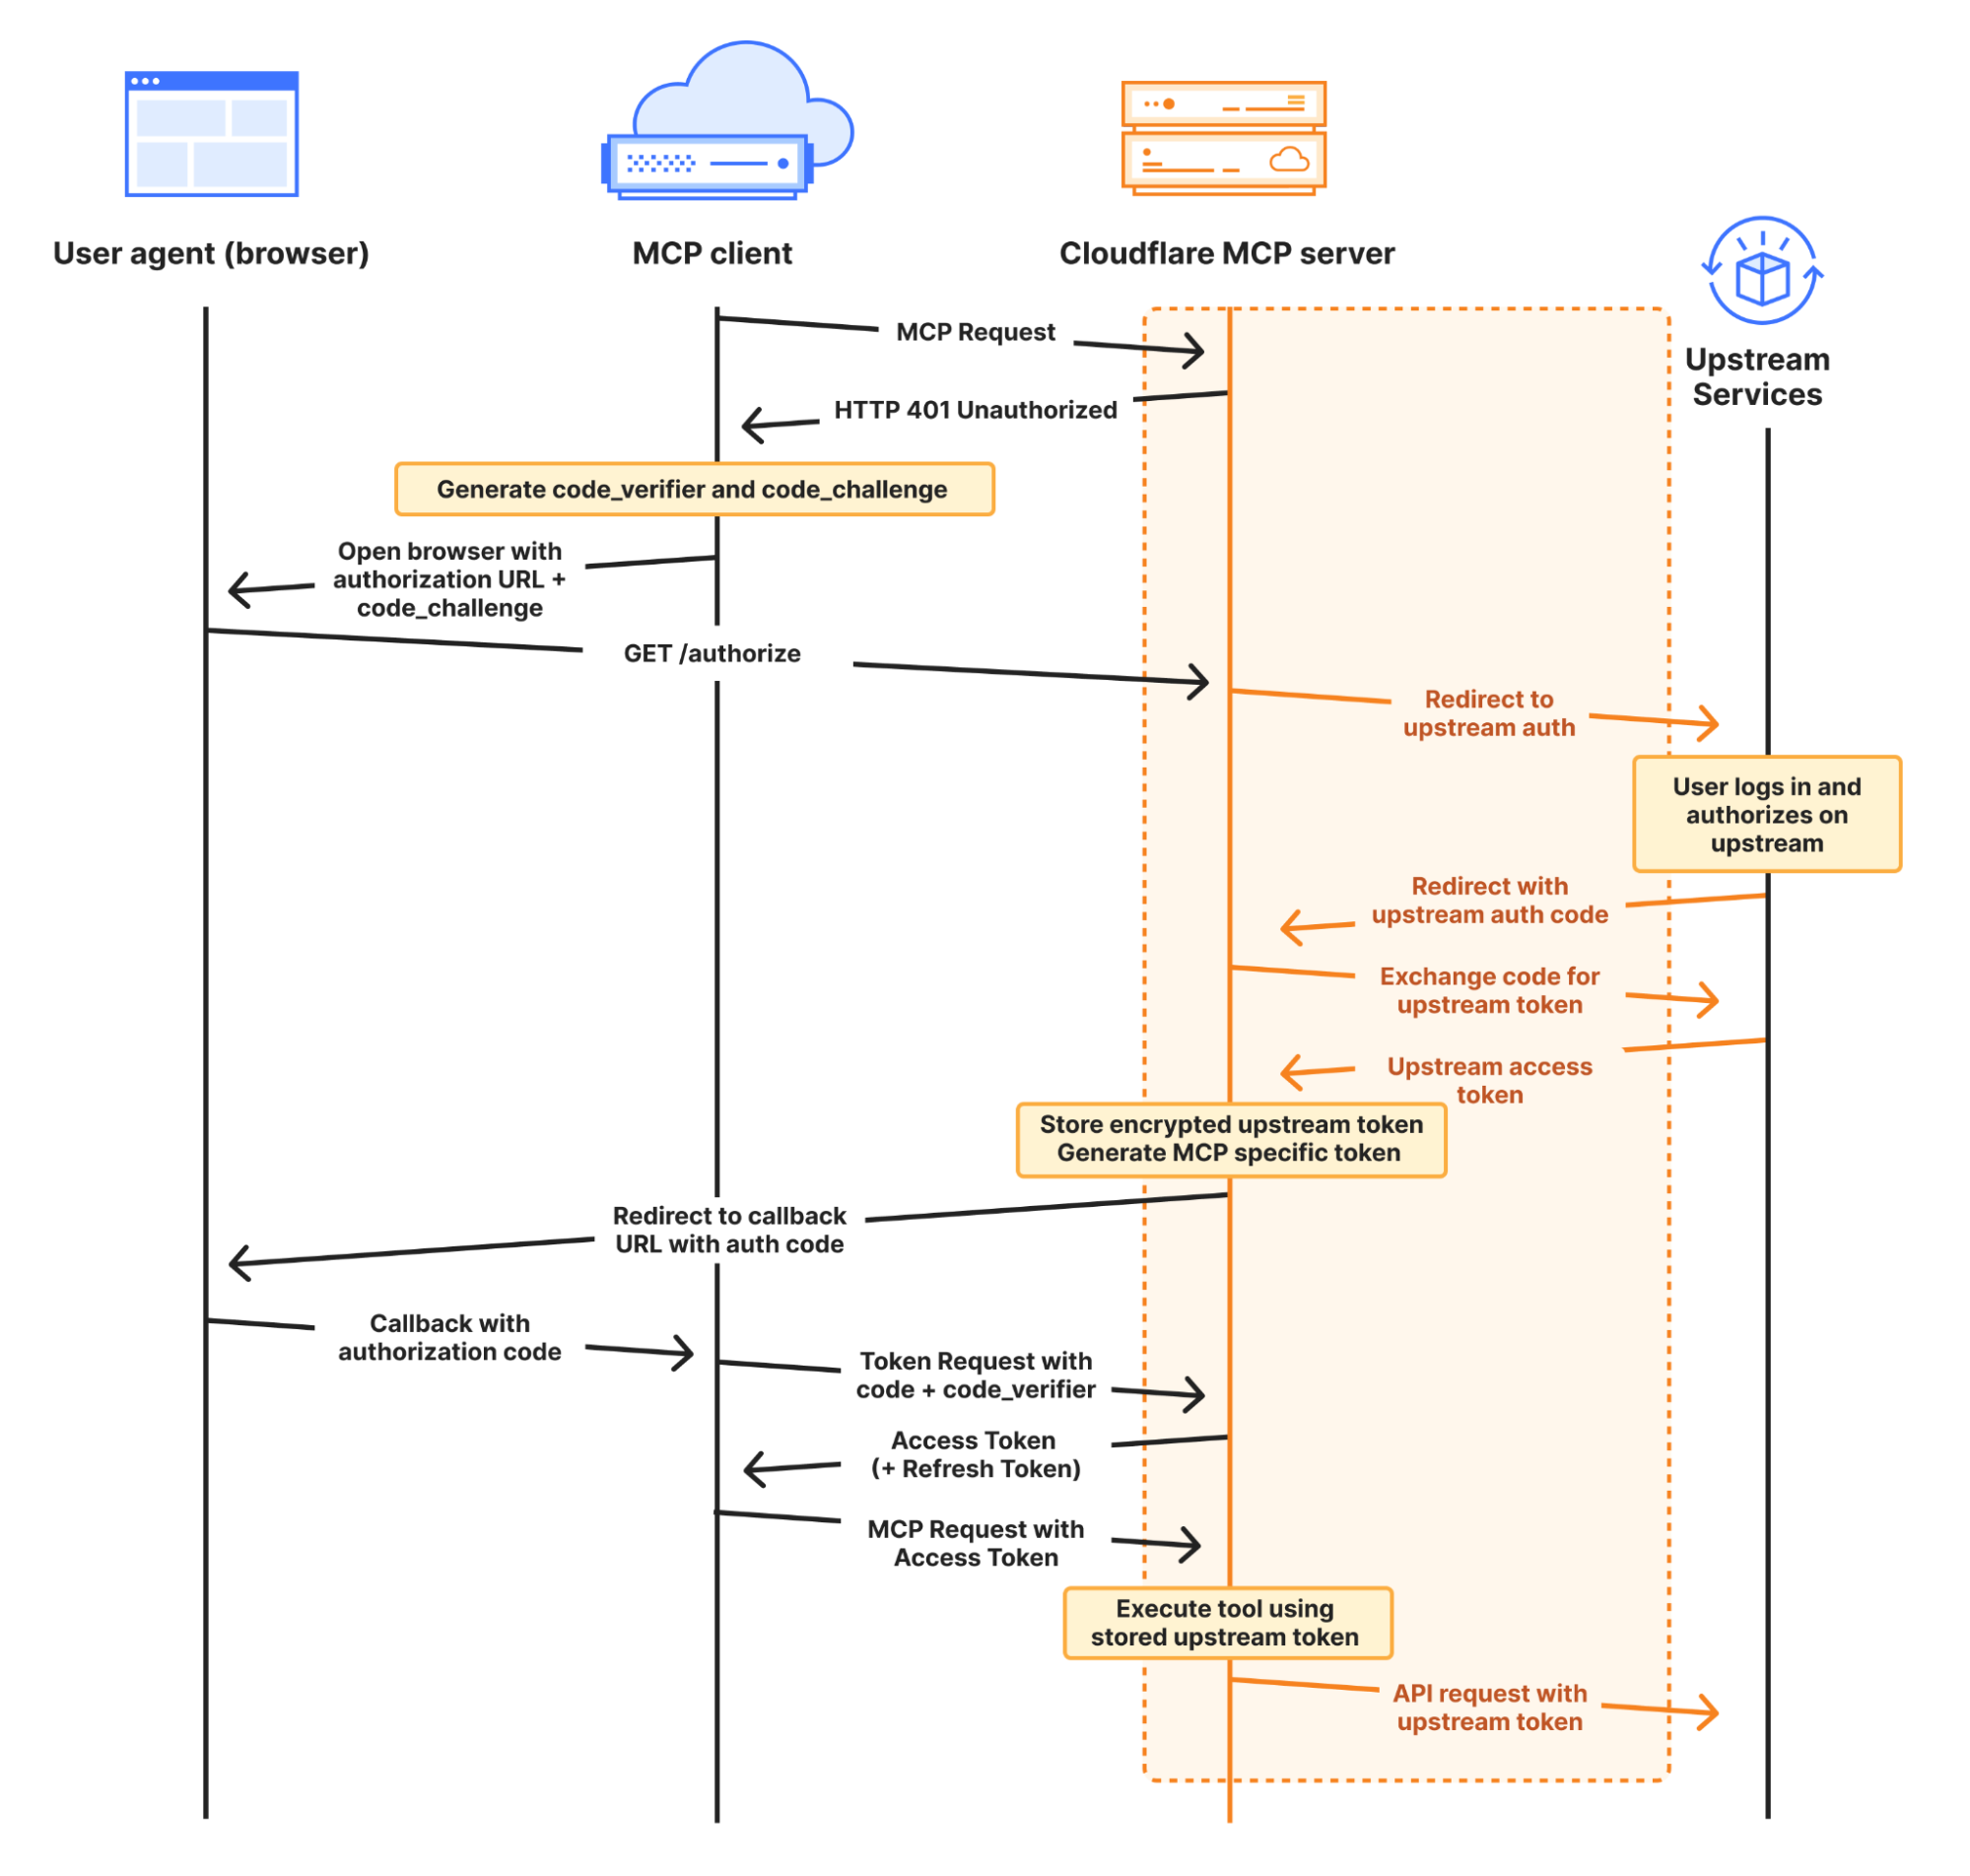
MCP does this with OAuth, which has been the standard protocol that allows users to grant applications to access their information or services, without sharing passwords. Here, the MCP Server itself acts as the OAuth Provider. However, OAuth with MCP is hard to implement yourself, so when you build MCP servers on Cloudflare we provide it for you.
workers-oauth-provider — an OAuth 2.1 Provider library for Cloudflare Workers
When you deploy an MCP Server to Cloudflare, your Worker acts as an OAuth Provider, using workers-oauth-provider, a new TypeScript library that wraps your Worker’s code, adding authorization to API endpoints, including (but not limited to) MCP server API endpoints.
Your MCP server will receive the already-authenticated user details as a parameter. You don’t need to perform any checks of your own, or directly manage tokens. You can still fully control how you authenticate users: from what UI they see when they log in, to which provider they use to log in. You can choose to bring your own third-party authentication and authorization providers like Google or GitHub, or integrate with your own.
Here, your MCP server acts as both an OAuth client to your upstream service, and as an OAuth server (also referred to as an OAuth “provider”) to MCP clients. You can use any upstream authentication flow you want, but workers-oauth-provider guarantees that your MCP server is spec-compliant and able to work with the full range of client apps & websites. This includes support for Dynamic Client Registration (RFC 7591) and Authorization Server Metadata (RFC 8414).
A simple, pluggable interface for OAuth
When you build an MCP server with Cloudflare Workers, you provide an instance of the OAuth Provider paths to your authorization, token, and client registration endpoints, along with handlers for your MCP Server, and for auth:
import OAuthProvider from "@cloudflare/workers-oauth-provider";
import MyMCPServer from "./my-mcp-server";
import MyAuthHandler from "./auth-handler";

export default new OAuthProvider({
  apiRoute: "/sse", // MCP clients connect to your server at this route
  apiHandler: MyMCPServer.mount('/sse'), // Your MCP Server implmentation
  defaultHandler: MyAuthHandler, // Your authentication implementation
  authorizeEndpoint: "/authorize",
  tokenEndpoint: "/token",
  clientRegistrationEndpoint: "/register",
});
This abstraction lets you easily plug in your own authentication. Take a look at this example that uses GitHub as the identity provider for an MCP server, in less than 100 lines of code, by implementing /callback and /authorize routes.
Why do MCP servers issue their own tokens?
You may have noticed in the authorization diagram above, and in the authorization section of the MCP spec, that the MCP server issues its own token to the MCP client.
Instead of passing the token it receives from the upstream provider directly to the MCP client, your Worker stores an encrypted access token in Workers KV. It then issues its own token to the client. As shown in the GitHub example above, this is handled on your behalf by the workers-oauth-provider — your code never directly handles writing this token, preventing mistakes. You can see this in the following code snippet from the GitHub example above:
  // When you call completeAuthorization, the accessToken you pass to it
  // is encrypted and stored, and never exposed to the MCP client
  // A new, separate token is generated and provided to the client at the /token endpoint
  const { redirectTo } = await c.env.OAUTH_PROVIDER.completeAuthorization({
    request: oauthReqInfo,
    userId: login,
    metadata: { label: name },
    scope: oauthReqInfo.scope,
    props: {
      accessToken,  // Stored encrypted, never sent to MCP client
    },
  })

  return Response.redirect(redirectTo)
On the surface, this indirection might sound more complicated. Why does it work this way?
By issuing its own token, MCP Servers can restrict access and enforce more granular controls than the upstream provider. If a token you issue to an MCP client is compromised, the attacker only gets the limited permissions you’ve explicitly granted through your MCP tools, not the full access of the original token.
Let’s say your MCP server requests that the user authorize permission to read emails from their Gmail account, using the gmail.readonly scope. The tool that the MCP server exposes is more narrow, and allows reading travel booking notifications from a limited set of senders, to handle a question like “What’s the check-out time for my hotel room tomorrow?” You can enforce this constraint in your MCP server, and if the token you issue to the MCP client is compromised, because the token is to your MCP server — and not the raw token to the upstream provider (Google) — an attacker cannot use it to read arbitrary emails. They can only call the tools your MCP server provides. OWASP calls out “Excessive Agency” as one of the top risk factors for building AI applications, and by issuing its own token to the client and enforcing constraints, your MCP server can limit tools access to only what the client needs.
Or building off the earlier GitHub example, you can enforce that only a specific user is allowed to access a particular tool. In the example below, only users that are part of an allowlist can see or call the generateImage tool, that uses Workers AI to generate an image based on a prompt:
import { McpAgent } from "agents/mcp";
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { z } from "zod";

const USER_ALLOWLIST = ["geelen"];

export class MyMCP extends McpAgent<Props, Env> {
  server = new McpServer({
    name: "Github OAuth Proxy Demo",
    version: "1.0.0",
  });

  async init() {
    // Dynamically add tools based on the user's identity
    if (USER_ALLOWLIST.has(this.props.login)) {
      this.server.tool(
        'generateImage',
        'Generate an image using the flux-1-schnell model.',
        {
          prompt: z.string().describe('A text description of the image you want to generate.')
        },
        async ({ prompt }) => {
          const response = await this.env.AI.run('@cf/black-forest-labs/flux-1-schnell', {
            prompt,
            steps: 8
          })
          return {
            content: [{ type: 'image', data: response.image!, mimeType: 'image/jpeg' }],
          }
        }
      )
    }
  }
}
Introducing McpAgent: remote transport support that works today, and will work with the revision to the MCP spec
The next step to opening up MCP beyond your local machine is to open up a remote transport layer for communication. MCP servers you run on your local machine just communicate over stdio, but for an MCP server to be callable over the Internet, it must implement remote transport.
The McpAgent class we introduced today as part of our Agents SDK handles this for you, using Durable Objects behind the scenes to hold a persistent connection open, so that the MCP client can send server-sent events (SSE) to your MCP server. You don’t have to write code to deal with transport or serialization yourself. A minimal MCP server in 15 lines of code can look like this:
import { McpAgent } from "agents/mcp";
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { z } from "zod";

export class MyMCP extends McpAgent {
  server = new McpServer({
    name: "Demo",
    version: "1.0.0",
  });
  async init() {
    this.server.tool("add", { a: z.number(), b: z.number() }, async ({ a, b }) => ({
      content: [{ type: "text", text: String(a + b) }],
    }));
  }
}
After much discussion, remote transport in the MCP spec is changing, with Streamable HTTP replacing HTTP+SSE This allows for stateless, pure HTTP connections to MCP servers, with an option to upgrade to SSE, and removes the need for the MCP client to send messages to a separate endpoint than the one it first connects to. The McpAgent class will change with it and just work with streamable HTTP, so that you don’t have to start over to support the revision to how transport works.
This applies to future iterations of transport as well. Today, the vast majority of MCP servers only expose tools, which are simple remote procedure call (RPC) methods that can be provided by a stateless transport. But more complex human-in-the-loop and agent-to-agent interactions will need prompts and sampling. We expect these types of chatty, two-way interactions will need to be real-time, which will be challenging to do well without a bidirectional transport layer. When that time comes, Cloudflare, the Agents SDK, and Durable Objects all natively support WebSockets, which enable full-duplex, bidirectional real-time communication.
Stateful, agentic MCP servers
When you build MCP servers on Cloudflare, each MCP client session is backed by a Durable Object, via the Agents SDK. This means each session can manage and persist its own state, backed by its own SQL database.
This opens the door to building stateful MCP servers. Rather than just acting as a stateless layer between a client app and an external API, MCP servers on Cloudflare can themselves be stateful applications — games, a shopping cart plus checkout flow, a persistent knowledge graph, or anything else you can dream up. When you build on Cloudflare, MCP servers can be much more than a layer in front of your REST API.
To understand the basics of how this works, let’s look at a minimal example that increments a counter:
import { McpAgent } from "agents/mcp";
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { z } from "zod";

type State = { counter: number }

export class MyMCP extends McpAgent<Env, State, {}> {
  server = new McpServer({
    name: "Demo",
    version: "1.0.0",
  });

  initialState: State = {
    counter: 1,
  }

  async init() {
    this.server.resource(`counter`, `mcp://resource/counter`, (uri) => {
      return {
        contents: [{ uri: uri.href, text: String(this.state.counter) }],
      }
    })

    this.server.tool('add', 'Add to the counter, stored in the MCP', { a: z.number() }, async ({ a }) => {
      this.setState({ ...this.state, counter: this.state.counter + a })

      return {
        content: [{ type: 'text', text: String(`Added ${a}, total is now ${this.state.counter}`) }],
      }
    })
  }

  onStateUpdate(state: State) {
    console.log({ stateUpdate: state })
  }

}
For a given session, the MCP server above will remember the state of the counter across tool calls.
From within an MCP server, you can use Cloudflare’s whole developer platform, and have your MCP server spin up its own web browser, trigger a Workflow, call AI models, and more. We’re excited to see the MCP ecosystem evolve into more advanced use cases.
Connect to remote MCP servers from MCP clients that today only support local MCP
Cloudflare is supporting remote MCP early — before the most prominent MCP client applications support remote, authenticated MCP, and before other platforms support remote MCP. We’re doing this to give you a head start building for where MCP is headed.
But if you build a remote MCP server today, this presents a challenge — how can people start using your MCP server if there aren’t MCP clients that support remote MCP?
We have two new tools that allow you to test your remote MCP server and simulate how users will interact with it in the future:
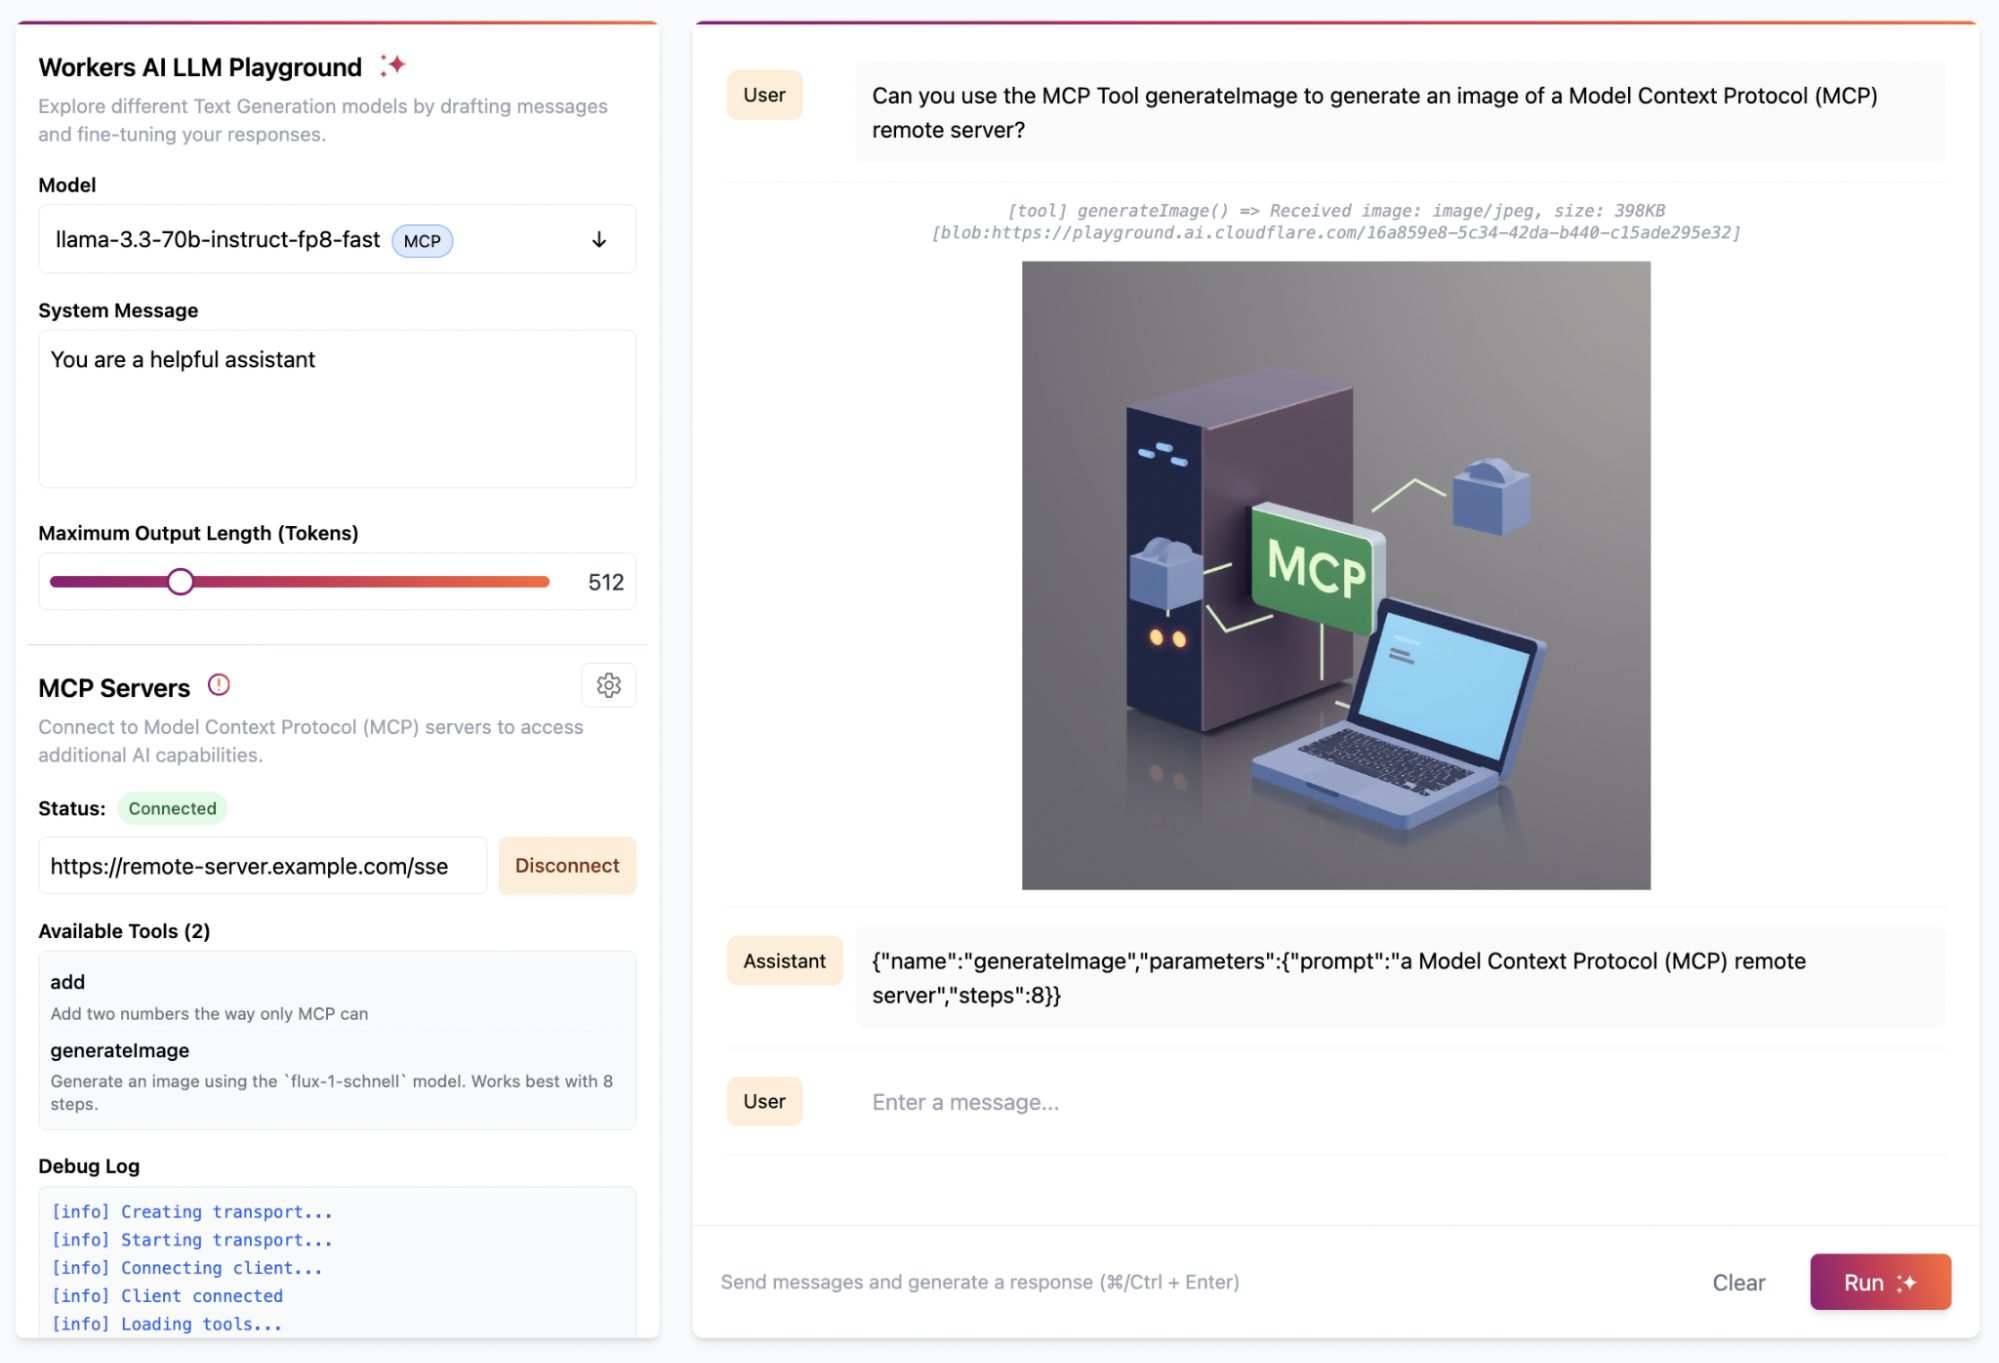
We updated the Workers AI Playground to be a fully remote MCP client that allows you to connect to any remote MCP server with built-in authentication support. This online chat interface lets you immediately test your remote MCP servers without having to install anything on your device. Instead, just enter the remote MCP server’s URL (e.g. https://remote-server.example.com/sse) and click Connect.
Once you click Connect, you’ll go through the authentication flow (if you set one up) and after, you will be able to interact with the MCP server tools directly from the chat interface.
If you prefer to use a client like Claude Desktop or Cursor that already supports MCP but doesn’t yet handle remote connections with authentication, you can use mcp-remote. mcp-remote is an adapter that lets MCP clients that otherwise only support local connections to work with remote MCP servers. This gives you and your users the ability to preview what interactions with your remote MCP server will be like from the tools you’re already using today, without having to wait for the client to support remote MCP natively.
We’ve published a guide on how to use mcp-remote with popular MCP clients including Claude Desktop, Cursor, and Windsurf. In Claude Desktop, you add the following to your configuration file:
Remote Model Context Protocol (MCP) is coming! When client apps support remote MCP servers, the audience of people who can use them opens up from just us, developers, to the rest of the population — who may never even know what MCP is or stands for.
Building a remote MCP server is the way to bring your service into the AI assistants and tools that millions of people use. We’re excited to see many of the biggest companies on the Internet are busy building MCP servers right now, and we are curious about the businesses that pop-up in an agent-first, MCP-native way.
On Cloudflare, you can start building today. We’re ready for you, and ready to help build with you. Email us at [email protected], and we’ll help get you going. There’s lots more to come with MCP, and we’re excited to see what you build.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.