The European Space Agency (ESA) is a 22-member intergovernmental body devoted to space exploration. Headquartered in Paris and with a global staff of around 2,200, the ESA was founded in 1975. Its annual budget was €7.08 billion in 2023.
Table of Contents
The challenge
The Columbus laboratory is the European module of the International Space Station and the cornerstone of Europe’s participation. Positioned on the starboard side of the Station’s leading edge, it is designed to provide an environment for pursuing research and development in a wide variety of fields. Its characteristics include:
Payload complement flexibility, provided by a modular design and serviced by a regular logistics, maintenance, and upgrade capability
A permanent crew presence for servicing payload support systems and interacting with payloads
A continuously available ground infrastructure for monitoring and controlling onboard activities
Columbus provides internal payload accommodation for multidisciplinary research into material science, fluid physics, and life sciences, while the External Payload Facility (EPF) hosts space science and Earth observation payloads.
Academics on Earth perform their tests on Columbus remotely – programming them and getting the results. The infrastructure required for these tests and the payloads that get sent back and forth require a flexible and dependable monitoring solution, and that’s where Zabbix enters the picture.
The solution
Zabbix proxy was deployed in the Columbus module alongside other software required for research, operations, and connectivity. The Zabbix server and frontend are deployed in the ground data center, and this is what the proxy communicates with.
In addition to proxies, we have a Zabbix sender and Agent 2 that are used on this infrastructure, which is made of VMS and containers running different kinds of services. Data is collected in a very ordinary fashion – Zabbix Agent 2 performs native checks because there is still server hardware running with operating systems and OS level resources that need to be monitored by the Agent.
We mix these native checks with user parameters which execute custom checks based on scripts or commands for commercial off-the-shelf components. The agent is extended depending on the requirements of the components. It then collects those metrics and sends them to the proxy. Scripting is used for custom components, and because Zabbix is language agnostic, any type of programming or scripting language works. It gets wrapped together with Zabbix sender, which then sends data to the proxy, which then sends data to the server.
Because there are so many custom services and metrics that need to be monitored (the number of high priority files in the transfer queue for a particular payload, for example) and because metrics, services, and payloads can change over time, the ESA needed to automate a way of automatically discovering these, displaying them, and collecting data for them. We used low-level discovery together with some scripting to discover and automatically start monitoring new payloads.
The results
Thanks to Zabbix’s visualization capabilities, the ESA’s team has found it easy to observe their dashboards and react to alerts in real time.
The ESA has also found Zabbix proxy to be an ideal solution for their needs, because if a link between the ground data center and the Columbus module goes down, the proxy keeps collecting local metrics, stores them in its own database, and then sends them back to the ground once the connection is restored. No such situation has arisen yet, but Zabbix has performed flawlessly in all test scenarios.
Monitoring is a never-ending process and there’s always room for improvement, but it’s reasonable to expect that the ESA will continue working on Zabbix and finding new metrics and new ways of improving monitoring.
In conclusion
Part of the beauty of Zabbix has always been its adaptability – it can be as simple or as complex as any user needs it to be. The simplicity of the Zabbix setup in this scenario (as opposed to a more modular setup with 4 or 5 pieces of software) is what makes it ideal for deployment by the ESA on the International Space Station.
To learn more about what we do for customers across multiple industries, visit our website or request a demo.
Through Code Club and CoderDojo we support the world’s largest network of free informal computing clubs for young people.
Code Club is a global network of after-school coding clubs for learners aged 9 to 13, where educators and other volunteers help young people learn about coding and digital making
CoderDojo is a worldwide network of free, open, and community-based programming clubs for young people aged 7 to 17, where they get the opportunity to learn how to create fantastic new things with technology
The clubs network reaches young people in 126 countries across the globe, and we estimate that the 4,557 Code Clubs and 771 CoderDojos are attended by more than 200,000 young people globally.
All these clubs are run by incredible volunteers and educators who help young people to learn computing and coding. Every year, we ask the volunteers to tell us about their experiences in our annual clubs survey. Below we share some highlights from this year’s survey results.
About the survey
We want to know more about volunteers in the network, how they run their clubs, and what impact the club sessions have for young people. Understanding this better helps us to improve the support we give to volunteers and young people around the world. This year we received over 300 responses, which has given us valuable insights and feedback.
What are the clubs like?
Improving gender balance in computing is part of our work to ensure equitable learning opportunities for all young people. Girls’ participation in the CodeDojo community has risen from 30% to 35% between 2023 and 2024, while 40% of Code Club attendees are girls.
Clubs are using a wide variety of technologies and tools to support young people with their coding. According to the survey, the most popular coding tool was Scratch, which nearly all of the volunteers said they used in their club. Over 60% of volunteers reported using micro:bits, and over 50% mentioned Python.
What impact is the clubs network having?
We asked volunteers to tell us what changes they had seen in young people as a result of being part of a club. Volunteers fed back to us about the positive community created by clubs where young people felt safe and included. This was evidenced by the way young people felt able to share their ideas and support other young people:
“The more experienced members are both capable and competent to demonstrate their skills to less experienced children. For example, they recently ran a full-day session for the whole school to complete the Astro Pi Mission Zero project.” – Code Club volunteer
Volunteers reported increases in young people’s skills and confidence in digital making and engaging with technology (see graph below). They also agreed that young people developed other skills, with nearly 90% noting improvements in problem solving, personal confidence, and creative thinking.
How are we supporting volunteers?
These positive outcomes are the result of the hard work and dedication of the club volunteers. Based on the survey, we estimate that at the time of the survey, there were over 6000 Code Club leaders and almost 3000 CoderDojo champions around the world. Many of the volunteers are motivated to volunteer by a love of teaching and a desire to pass on their skills.
These volunteers are part of a global network, and 80% of volunteers said that belonging to this global community of clubs was motivating for them. Volunteers particularly valued the access to resources and information being part of a global community offered, as well as opportunities to share ideas and problem solve.
The majority of Code Clubs are mostly or always using our digital making pathways and projects as part of their clubs. Volunteers value the projects’ step-by-step structure and how easy they are to follow.
We plan to do more to ensure that clubs around the world find these projects and pathways accessible and useful for their sessions with young people.
What’s next
The survey has helped us to identify a number of areas where we can support club volunteers even better. Volunteers identified help getting equipment and funding as the main things they needed support with, as well as recruitment of volunteers and young people. We are looking at the best ways we can lend a hand to the clubs network in these areas.
We take impact seriously and are always looking to understand how we can improve and increase the impact we have on the lives of children and young people. To find out more about our approach to impact, you can read about our recently updated theory of change, which supports how we evaluate what we do.
Идеята за тази необичайна (в сравнение с повечето ми публикации в „Тоест“) статия се породи като следствие от предишната – за т.нар. борба с дрогата в България. За една тема, която възнамерявах да засегна накратко, накрая не се намери място. След това с редакцията преценихме, че тя заслужава самостоятелно внимание. Темата е: какво разбираме под „наркотици“. Както и под „зависимост“ изобщо. И тъй като вникването в проблема е свързано с поставянето на всекидневни очевидности под въпрос, избрах да пиша в първо лице и да споделя личен опит, вместо да застана на привидно неутрална анализаторска позиция.
Къде съм в картинката
Не пуша и никога не съм пробвала – нито тютюн, нито нещо друго. Не пия и нищо по-алкохолно от боза (не от убеждение, просто вкусът ми е гаден), така че съм нямала възможност да разбера какво е да се напиеш. И наркотици не съм вземала. Освен може би веднъж, когато ми дадоха едно кексче и ми казаха, че от него ще ми стане хубаво. Чак след като го глътнах, схванах какво всъщност са ми казали. Е, никаква промяна не усетих.
От тийнейджърка обаче всекидневно пия чай. Нямаше да мога да напиша никоя от статиите си, без да се подкрепя със силен черен чай. А понякога, когато чаят не е достатъчен, за да влезе мозъкът ми в работен режим, си помагам и с хрупане на какаови зърна. Така направих и днес.
Много хора ми се смеят, когато кажа, че да, не пуша, не пия, не се друсам, но съм зависима от чая. Мой приятел с дългогодишен опит в злоупотребяването с различни наркотици прие твърдението ми сериозно и рече: „Ами чаят е спийд“. „Спийд“ е жаргонно название за наркотиците, които действат стимулиращо – като амфетамините например.
Две понятия за дрога
Когато говорим за дрога, обикновено имаме предвид наркотични вещества, които в повечето случаи законът признава за такива и които са под строга регулация, често са и забранени. Наркотици в този смисъл са например – при всички разлики във въздействието и рисковаността на употребата им – марихуаната, хероинът, кокаинът, амфетамините, LSD-то, разни модерни „дизайнерски“ дроги и пр.
Някои наркотици се промъкват покрай законовите регулации. Като балоните с райски газ, чиято продажба накрая уж беше забранена за непълнолетни, но забраната е широко нарушавана. Или в миналото дишането на лепило „Кале“ заради ацетона в него.
Други наркотици са допустими за използване в медицината, но не се продават свободно – например упойките и лекарствата, изписвани с жълта и зелена рецепта.
В широкия смисъл на думата обаче дрога са всички психоактивни вещества, тоест веществата, които по един или друг начин влияят на съзнанието. От тази гледна точка и алкохолът, и тютюнът са дрога. Но също и кафето, чаят (растението чай, а не отвари от други билки, някои от които впрочем също съдържат психоактивни вещества), захарта, кока-колата, да не говорим за енергийните напитки. И още много съвсем легални храни и напитки.
Наркотици и зависимост
Как се решава кой продукт, водещ до промяна в съзнанието, да се обяви за наркотик и кой – не? Дали критерият е зависимостта, която може да се развие при употребата? Надали – далеч не всички наркотици предизвикват зависимост като хероина. От друга страна, алкохолът и тютюнът могат да доведат до тежка зависимост. Човек се пристрастява и към кафето, чая, захарта и пр.
Освен това зависимостта може да бъде чисто психическа, без да е свързана с физическата консумация на вещество или продукт. Добре известно е например, че човек може да се пристрасти към хазарта. Въпреки това безогледната реклама на хазарт в България беше ограничена едва наскоро. И още е рано да се каже дали и доколко ограниченията ще работят.
Зависимост може да се развие и към неща, смятани за безвредни, а някои дори за необходими и полезни. Свикнали сме да се говори за пристрастяване към компютърни игри, интернет и мобилни телефони или към телевизия. Но зависимостта може да бъде и към работата, секса, спорта и какво ли още не, дори към четенето.
Склонни сме обаче да забелязваме едни форми на зависимост повече от други. Ако някой си гледа само в телефона, това може да се интерпретира като пристрастяване, все едно каква дейност извършва този човек с помощта на телефона. Но ако някой чете книга (стига да не я чете от телефона си), това се смята за достойно за душата. Независимо че и в двата случая става въпрос за еднакво дълбока погълнатост от дейността, принудителното изваждане от която би предизвикало аналогичен дискомфорт.
Антисоциални ли са зависимостите?
Широко разпространено е схващането, че дрогирането, алкохолизмът и изобщо зависимостите са нещо антисоциално. Понякога действително става въпрос за контракултурно бунтарство. В много случаи обаче причината е тъкмо обратната – човек стига до зависимост поради усилията си да се впише в обществото и/или да функционира пълноценно в него.
Това, че не пропуших, беше един от факторите да съм сред аутсайдерите в училище. А понеже и не пия, многократно съм била под социален натиск. „Ама само една чашка няма ли да пийнеш?“ „Няма да чукна наздравица с теб, защото си на безалкохолно!“ Понякога дори съм нямала възможност да откажа да ми сипят алкохол. В един период си бях решила проблема с наздравиците, като лъжех, че в кока-колата ми има водка.
Един бивш колега, който пък не пиеше поради алкохолизъм, от срам да не се разкрие зависимостта му тайно даваше питието си на друг колега, който поради това поглъщаше двойно количество и се напиваше. Друг познат, уволняван заради проблемите си с алкохола, реторично питаше: „Как да ходя на служебни купони, като там се пие?“.
Някои вземат наркотици, за да се справят по-добре с работата си. Не става дума само за представители на творческите професии, като музикантите. Амфетамините могат да допринесат например за по-добра концентрация и работоспособност при хора, на които кафето и чаят не са им достатъчни.
Може би дрогата, свързана с най-голяма стигма, е хероинът. Но няма да забравя разговора си с един здравен медиатор в ромски квартал, който ми разказваше за хероинозависимите мъже от махалата. Попитах го кое ги кара да посегнат към този наркотик. Отговори, че те работят тежък физически труд. Идва някой и им казва, че ако си бият една инжекция, ще имат сили и няма да се уморяват. Първите пъти наистина усещат прилив на сили. После вече става късно.
Изобщо, дрогирането в името на социалното функциониране е нож с две остриета, независимо дали говорим за „сериозни“ наркотици, алкохол, или за кафе и т.н. Черният чай и какаовите зърна може да ми помагат да работя, но не питайте как ще заспя след това. Има хора, които не могат да заспят без алкохол или приспивателно (в което се съдържат наркотични вещества), след като през деня са изпили сума ти кафета, за да са в състояние да работят.
Разнообразното отношение към дрогите
Причините едни психоактивни продукти и вещества да са легални дори за деца, ползването на други да е възможно при определени условия, а трети да са абсолютно забранени, не са в самите продукти или вещества. Те са културни, политически, религиозни, географски, икономически.
Марихуаната може би нямаше да бъде толкова „демонизирана“, ако от растението коноп не се произвеждаха толкова много продукти, между които плат, хартия, биогориво, строителни и изолационни материали. Съответно криминализирането на конопа е от полза за производителите на „конкурентни“ стоки – памук, за петролната индустрия, дървопреработването и още доста бизнеси. Колкото и абсурдно да е това, защото индустриалният коноп е нещо различно от видовете на растението, които се използват като наркотик.
В САЩ консумацията на алкохол е забранена до 21-годишна възраст, а на открити места е възможна само ако бутилката е скрита в плик. Същевременно лекарите масово предписват лекарства, към които пациентите лесно се пристрастяват. В Германия отношението към алкохола е далеч по-либерално, но до медикаменти, предизвикващи зависимост, се прибягва само ако няма други варианти. Дори след операция на пациента може да се даде само ибупрофен. И да му се обясни, че не е толкова страшно да се научи да понася някаква болка.
В Чили масово се пие чай от кока, а ако сте на голяма надморска височина в Андите, без този чай трудно ще останете в съзнание. В случай че решите да си донесете такъв чай в България обаче, се излагате на сериозен риск. Затова пък тук маковото семе го продават в магазините, но ако си занесете някое пакетче в Сингапур, може да си имате големи неприятности.
За разлика от исляма, християнството разрешава алкохола, а при вземането на причастие консумацията му дори е задължителна. Най-последователни по отношение на психоактивните вещества са мормоните, които забраняват не само алкохола, а и кафето и чая.
Необходимост или конвенция?
Като се замислим, някой, изпил десет кафета, може да представлява сериозен риск за пътното движение поради нервността и прилива на енергия от многото кофеин. Но от законова гледна точка не е извършил нарушение, „надрусвайки се“ с кафе. Друг човек, който страда от епилепсия, не получава припадъци само ако всекидневно приема бензодиазепинови лекарства. Но употребата им ще даде положителен тест за наркотици. Трети може да пие амфетамини, които са му предписани, за да се справя с дефицита си на внимание, който му пречи да шофира безопасно. Четвърти може да причини катастрофа именно защото не си е пил лекарствата от страх да не даде положителен тест.
Подобни парадокси виждаме и в останалите сфери от живота. Злоупотребата с алкохол например може да направи някого много по-агресивен от напушването с трева, но алкохолът се продава свободно в магазините, докато марихуаната е на специален режим дори в страните, в които е легализирана.
Накратко, отношението към едни или други психоактивни вещества, както и правното им регулиране не са пряка функция от тяхното въздействие. Има ред други причини – от културни специфики до корпоративни войни. Без да пренебрегваме корупцията и огромния черен пазар, свързан с производството и разпространението на нелегални субстанции.
Затова, преди да сочим с пръст „дрогираните“, „наркоманите“, „пияните“ или „алкохолиците“, е добре да се опитаме да си дадем сметка за собствените си зависимости. Разделянето на „ние“ и „другите“ е изпитан популистки трик. Но в повечето случаи просто не е честно. И говори за други зависимости.
A proposal to switch the default desktop for Fedora Workstation from GNOME
to KDE Plasma largely went over like the proverbial lead balloon—unsurprisingly.
But the
conversation about the proposal did surface some areas where the
distribution could
perhaps be more inclusive with regard to the other desktop choices
available. The project believes that it
benefits from being opinionated and not requiring users to make
multiple decisions before they can even install the distribution, but there
is a balance
to be found.
Today, we’re happy to welcome a new member of the Amazon Titan family of models: Amazon Titan Text Premier, now available in Amazon Bedrock.
Following Amazon Titan Text Lite and Titan Text Express, Titan Text Premier is the latest large language model (LLM) in the Amazon Titan family of models, further increasing your model choice within Amazon Bedrock. You can now choose between the following Titan Text models in Bedrock:
Titan Text Premier is the most advanced Titan LLM for text-based enterprise applications. With a maximum context length of 32K tokens, it has been specifically optimized for enterprise use cases, such as building Retrieval Augmented Generation (RAG) and agent-based applications with Knowledge Bases and Agents for Amazon Bedrock. As with all Titan LLMs, Titan Text Premier has been pre-trained on multilingual text data but is best suited for English-language tasks. You can further custom fine-tune (preview) Titan Text Premier with your own data in Amazon Bedrock to build applications that are specific to your domain, organization, brand style, and use case. I’ll dive deeper into model highlights and performance in the following sections of this post.
Titan Text Express is ideal for a wide range of tasks, such as open-ended text generation and conversational chat. The model has a maximum context length of 8K tokens.
Titan Text Lite is optimized for speed, is highly customizable, and is ideal to be fine-tuned for tasks such as article summarization and copywriting. The model has a maximum context length of 4K tokens.
Now, let’s discuss Titan Text Premier in more detail.
Amazon Titan Text Premier model highlights Titan Text Premier has been optimized for high-quality RAG and agent-based applications and customization through fine-tuning while incorporating responsible artificial intelligence (AI) practices.
Optimized for RAG and agent-based applications – Titan Text Premier has been specifically optimized for RAG and agent-based applications in response to customer feedback, where respondents named RAG as one of their key components in building generative AI applications. The model training data includes examples for tasks like summarization, Q&A, and conversational chat and has been optimized for integration with Knowledge Bases and Agents for Amazon Bedrock. The optimization includes training the model to handle the nuances of these features, such as their specific prompt formats.
High-quality RAG through integration with Knowledge Bases for Amazon Bedrock – With a knowledge base, you can securely connect foundation models (FMs) in Amazon Bedrock to your company data for RAG. You can now choose Titan Text Premier with Knowledge Bases to implement question-answering and summarization tasks over your company’s proprietary data.
Automating tasks through integration with Agents for Amazon Bedrock – You can also create custom agents that can perform multistep tasks across different company systems and data sources using Titan Text Premier with Agents for Amazon Bedrock. Using agents, you can automate tasks for your internal or external customers, such as managing retail orders or processing insurance claims.
We already see customers exploring Titan Text Premier to implement interactive AI assistants that create summaries from unstructured data such as emails. They’re also exploring the model to extract relevant information across company systems and data sources to create more meaningful product summaries.
Here’s a demo video created by my colleague Brooke Jamieson that shows an example of how you can put Titan Text Premier to work for your business.
Custom fine-tuning of Amazon Titan Text Premier (preview) – You can fine-tune Titan Text Premier with your own data in Amazon Bedrock to increase model accuracy by providing your own task-specific labeled training dataset. Customizing Titan Text Premier helps to further specialize your model and create unique user experiences that reflect your company’s brand, style, voice, and services.
Built responsibly – Amazon Titan Text Premier incorporates safe, secure, and trustworthy practices. The AWS AI Service Card for Amazon Titan Text Premier documents the model’s performance across key responsible AI benchmarks from safety and fairness to veracity and robustness. The model also integrates with Guardrails for Amazon Bedrock so you can implement additional safeguards customized to your application requirements and responsible AI policies. Amazon indemnifies customers who responsibly use Amazon Titan models against claims that generally available Amazon Titan models or their outputs infringe on third-party copyrights.
Amazon Titan Text Premier model performance Titan Text Premier has been built to deliver broad intelligence and utility relevant for enterprises. The following table shows evaluation results on public benchmarks that assess critical capabilities, such as instruction following, reading comprehension, and multistep reasoning against price-comparable models. The strong performance across these diverse and challenging benchmarks highlights that Titan Text Premier is built to handle a wide range of use cases in enterprise applications, offering great price performance. For all benchmarks listed below, a higher score is a better score.
Note: Benchmarks evaluate model performance using a variation of few-shot and zero-shot prompting. With few-shot prompting, you provide the model with a number of concrete examples (three for 3-shot, five for 5-shot, etc.) of how to solve a specific task. This demonstrates the model’s ability to learn from example, called in-context learning. With zero-shot prompting on the other hand, you evaluate a model’s ability to perform tasks by relying only on its preexisting knowledge and general language understanding without providing any examples.
Get started with Amazon Titan Text Premier To enable access to Amazon Titan Text Premier, navigate to the Amazon Bedrock console and choose Model access on the bottom left pane. On the Model access overview page, choose the Manage model access button in the upper right corner and enable access to Amazon Titan Text Premier.
To use Amazon Titan Text Premier in the Bedrock console, choose Text or Chat under Playgrounds in the left menu pane. Then choose Select model and select Amazon as the category and Titan Text Premier as the model. To explore the model, you can load examples. The following screenshot shows one of those examples that demonstrates the model’s chain of thought (CoT) and reasoning capabilities.
By choosing View API request, you can get a code example of how to invoke the model using the AWS Command Line Interface (AWS CLI) with the current example prompt. You can also access Amazon Bedrock and available models using the AWS SDKs. In the following example, I will use the AWS SDK for Python (Boto3).
Amazon Titan Text Premier in action For this demo, I ask Amazon Titan Text Premier to summarize one of my previous AWS News Blog posts that announced the availability of Amazon Titan Image Generator and the watermark detection feature.
For summarization tasks, a recommended prompt template looks like this:
The following is text from a {{Text Category}}:
{{Text}}
Summarize the {{Text Category}} in {{length of summary}}
I adapt this template to my example and define the prompt. In preparation, I saved my News Blog post as a text file and read it into the post string variable.
prompt = """
The following is text from a AWS News Blog post:

<text>
%s
</text>

Summarize the above AWS News Blog post in a short paragraph.
""" % post
Similar to previous Amazon Titan Text models, Amazon Titan Text Premier supports temperature and topP inference parameters to control the randomness and diversity of the response, as well as maxTokenCount and stopSequences to control the length of the response.
Amazon Titan Image Generator is now generally available in Amazon Bedrock, giving you an easy way to build and scale generative AI applications with new image generation and image editing capabilities, including instant customization of images. Watermark detection for Titan Image Generator is now generally available in the Amazon Bedrock console. Today, we’re also introducing a new DetectGeneratedContent API (preview) in Amazon Bedrock that checks for the existence of this watermark and helps you confirm whether an image was generated by Titan Image Generator.
More resources Here are some additional resources that you might find helpful:
Intended use cases and more — Check out the AWS AI Service Card for Amazon Titan Text Premier to learn more about the models’ intended use cases, design, and deployment, as well as performance optimization best practices.
Amazon Titan models — If you’re curious to learn more about Amazon Titan models in general, check out the following video. Dr. Sherry Marcus, Director of Applied Science for Amazon Bedrock, shares how the Amazon Titan family of models incorporates the 25 years of experience Amazon has innovating with AI and machine learning (ML) across its business.
Now available Amazon Titan Text Premier is available today in the AWS US East (N. Virginia) Region. Custom fine-tuning for Amazon Titan Text Premier is available today in preview in the AWS US East (N. Virginia) Region. Check the full Region list for future updates. To learn more about the Amazon Titan family of models, visit the Amazon Titan product page. For pricing details, review the Amazon Bedrock pricing page.
The Rapid7 Take Command Summit is just two short weeks away. We’re busy putting together one of the most impactful programs on the latest in cybersecurity trends, technology, and innovations available, and we are eager to share it with all of you.
So eager, in fact, that Chairman and CEO of Rapid7, Corey Thomas, has a special message to share.
The Take Command Summit is a chance to hear from industry leaders on up-to-the minute security research, trends, and intelligence; from ransomware and state-sponsored threats, to the marquee vulnerabilities making headlines around the globe.
At Take Command you will receive a glimpse into our elite security operations center (SOC); and understand the best ways to show your organization’s leadership how a robust security operation can actually improve your ROI. We will share our approach to building a world-class SOC with partners who truly understand your needs and what makes your security operations unique.
All of this is in service of what we call commanding the attack surface. It’s best expressed in our effort to anticipate, pinpoint, and act on imminent and active threats across your entire security ecosystem and foster a cultural shift that empowers every member of your organization to help keep your networks secure.
We think this is a critical conversation at a critical moment. We hope to see you there.
This post is written by Uri Segev, Principal Serverless Specialist SA.
When you invoke an AWS Lambda function synchronously, you expect the function to return a response. For example, this is the case when a client invokes a Lambda function through Amazon API Gateway or from AWS Step Functions. As the client is waiting for the response, you should return the response as soon as possible.
However, there may be instances where you must perform additional work that does not affect the response and you can do it asynchronously, after you send the response. For example, you may store data in a database or send information to a logging system.
Once you send the response from the function, the Lambda service freezes the runtime environment, and the function cannot run additional code. Even if you create a thread for running a task in the background, the Lambda service freezes the runtime environment once the handler returns, causing the thread to freeze until the next invocation. While you can delay returning the response to the client until all work is complete, this approach can negatively impact the user experience.
This blog explores ways to run a task that may start before the function returns but continues running after the function returns the response to the client.
Invoking an asynchronous Lambda function
The first option is to break the code into two functions. The first function runs the synchronous code; the second function runs the asynchronous code. Before the synchronous function returns, it invokes the second function asynchronously, either directly, using the Invoke API, or indirectly, for example, by sending a message to Amazon SQS to trigger the second function.
This Python code demonstrates how to implement this:
import json
import time
import os
import boto3
from aws_lambda_powertools import Logger

logger = Logger()
client = boto3.client('lambda')

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from async"
    }

def submit_async_task(response):
    # Invoke async function to continue
    logger.info(f"[Function] Invoking async task in async function")
    client.invoke_async(FunctionName=os.getenv('ASYNC_FUNCTION'), InvokeArgs=json.dumps(response))

def handler(event, context):
    logger.info(f"[Function] Received event: {json.dumps(event)}")

    response = calc_response(event)

    # Done calculating response, submit async task
    submit_async_task(response)

    # Return response to client
    logger.info(f"[Function] Returning response to client")
    return {
        "statusCode": 200,
        "body": json.dumps(response)
    }
The following is the Lambda function that performs the asynchronous work:
import json
import time
from aws_lambda_powertools import Logger

logger = Logger()

def handler(event, context):
    logger.info(f"[Async task] Starting async task: {json.dumps(event)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")
Use Lambda response streaming
Response streaming enables developers to start streaming the response as soon as they have the first byte of the response, without waiting for the entire response. You usually use response streaming when you must minimize the Time to First Byte (TTFB) or when you must send a response that is larger than 6 MB (the Lambda response payload size limit).
Using this method, the function can send the response using the response streaming mechanism and can continue running code even after sending the last byte of the response. This way, the client receives the response, and the Lambda function can continue running.
This Node.js code demonstrates how to implement this:
import { Logger } from '@aws-lambda-powertools/logger';

const logger = new Logger();

export const handler = awslambda.streamifyResponse(async (event, responseStream, _context) => {
    logger.info("[Function] Received event: ", event);

    // Do some stuff with event
    let response = await calc_response(event);

    // Return response to client
    logger.info("[Function] Returning response to client");
    responseStream.setContentType('application/json');
    responseStream.write(response);
    responseStream.end();

    await async_task(response);
});

const calc_response = async (event) => {
    logger.info("[Function] Calculating response");
    await sleep(1);  // Simulate sync work

    return {
        message: "hello from streaming"
    };
};

const async_task = async (response) => {
    logger.info("[Async task] Starting async task");
    await sleep(3);  // Simulate async work
    logger.info("[Async task] Done");
};

const sleep = async (sec) => {
    return new Promise((resolve) => {
        setTimeout(resolve, sec * 1000);
    });
};
Use Lambda extensions
Lambda extensions can augment Lambda functions to integrate with your preferred monitoring, observability, security, and governance tools. You can also use an extension to run your own code in the background so that it continues running after your function returns the response to the client.
There are two types of Lambda extensions: external extensions and internal extensions. External extensions run as separate processes in the same execution environment. The Lambda function can communicate with the extension using files in the /tmp folder or using a local network, for example, via HTTP requests. You must package external extensions as a Lambda layer.
Internal extensions run as separate threads within the same process that runs the handler. The handler can communicate with the extension using any in-process mechanism, such as internal queues. This example shows an internal extension, which is a dedicated thread within the handler process.
When the Lambda service invokes a function, it also notifies all the extensions of the invocation. The Lambda service only freezes the execution environment when the Lambda function returns a response and all the extensions signal to the runtime that they are finished. With this approach, the function has the extension run the task independently from the function itself and the extension notifies the Lambda runtime when it is done processing the task. This way, the execution environment stays active until the task is done.
The following Python code example isolates the extension code into its own file and the handler imports and uses it to run the background task:
import json
import time
import async_processor as ap
from aws_lambda_powertools import Logger

logger = Logger()

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from extension"
    }

# This function is performed after the handler code calls submit_async_task
# and it can continue running after the function returns
def async_task(response):
    logger.info(f"[Async task] Starting async task: {json.dumps(response)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")

def handler(event, context):
    logger.info(f"[Function] Received event: {json.dumps(event)}")

    # Calculate response
    response = calc_response(event)

    # Done calculating response
    # call async processor to continue
    logger.info(f"[Function] Invoking async task in extension")
    ap.start_async_task(async_task, response)

    # Return response to client
    logger.info(f"[Function] Returning response to client")
    return {
        "statusCode": 200,
        "body": json.dumps(response)
    }
The following Python code demonstrates how to implement the extension that runs the background task:
import os
import requests
import threading
import queue
from aws_lambda_powertools import Logger

logger = Logger()
LAMBDA_EXTENSION_NAME = "AsyncProcessor"

# An internal queue used by the handler to notify the extension that it can
# start processing the async task.
async_tasks_queue = queue.Queue()

def start_async_processor():
    # Register internal extension
    logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Registering with Lambda service...")
    response = requests.post(
        url=f"http://{os.environ['AWS_LAMBDA_RUNTIME_API']}/2020-01-01/extension/register",
        json={'events': ['INVOKE']},
        headers={'Lambda-Extension-Name': LAMBDA_EXTENSION_NAME}
    )
    ext_id = response.headers['Lambda-Extension-Identifier']
    logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Registered with ID: {ext_id}")

    def process_tasks():
        while True:
            # Call /next to get notified when there is a new invocation and let
            # Lambda know that we are done processing the previous task.

            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Waiting for invocation...")
            response = requests.get(
                url=f"http://{os.environ['AWS_LAMBDA_RUNTIME_API']}/2020-01-01/extension/event/next",
                headers={'Lambda-Extension-Identifier': ext_id},
                timeout=None
            )

            # Get next task from internal queue
            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Wok up, waiting for async task from handler")
            async_task, args = async_tasks_queue.get()

            if async_task is None:
                # No task to run this invocation
                logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Received null task. Ignoring.")
            else:
                # Invoke task
                logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Received async task from handler. Starting task.")
                async_task(args)

            logger.debug(f"[{LAMBDA_EXTENSION_NAME}] Finished processing task")

    # Start processing extension events in a separate thread
    threading.Thread(target=process_tasks, daemon=True, name='AsyncProcessor').start()

# Used by the function to indicate that there is work that needs to be
# performed by the async task processor
def start_async_task(async_task=None, args=None):
    async_tasks_queue.put((async_task, args))

# Starts the async task processor
start_async_processor()
Use a custom runtime
Lambda supports several runtimes out of the box: Python, Node.js, Java, Dotnet, and Ruby. Lambda also supports custom runtimes, which lets you develop Lambda functions in any other programming language that you need to.
When you invoke a Lambda function that uses a custom runtime, the Lambda service invokes a process called ‘bootstrap’ that contains your custom code. The custom code needs to interact with the Lambda Runtime API. It calls the /next endpoint to obtain information about the next invocation. This API call is blocking and it waits until a request arrives. When the function is done processing the request, it must call the /response endpoint to send the response back to the client and then it must call the /next endpoint again to wait for the next invocation. Lambda freezes the execution environment after you call /next, until a request arrives.
Using this approach, you can run the asynchronous task after calling /response, and sending the response back to the client, and before calling /next, indicating that the processing is done.
The following Python code example isolates the custom runtime code into its own file and the function imports and uses it to interact with the runtime API:
import time
import json
import runtime_interface as rt
from aws_lambda_powertools import Logger

logger = Logger()

def calc_response(event):
    logger.info(f"[Function] Calculating response")
    time.sleep(1) # Simulate sync work
    return {
        "message": "hello from custom"
    }

def async_task(response):
    logger.info(f"[Async task] Starting async task: {json.dumps(response)}")
    time.sleep(3)  # Simulate async work
    logger.info(f"[Async task] Done")

def main():
    # You can add initialization code here

    # The following loop runs forever waiting for the next invocation
    # and sending the response back to the client
    while True:
        # Call /next to wait for next request (and indicate
        # that we are done processing the previous request)

        requestId, event = rt.get_next()

        # The code from here to send_response() is the code
        # that usually goes inside the Lambda handler()

        logger.info(f"[Function] Received event: {json.dumps(event)}")

        # Calculate response
        response = calc_response(event)

        # Done calculating response, send response to client
        logger.info(f"[Function] Returning response to client")
        rt.send_response(requestId, {
            "statusCode": 200,
            "body": json.dumps(response)
        })

        logger.info(f"[Function] Invoking async task")
        async_task(response)

main()
This Python code demonstrates how to interact with the runtime API:
This blog shows four ways of combining synchronous and asynchronous tasks in a Lambda function, allowing you to run tasks that continue running after the function returns a response to the client. The following table summarizes the pros and cons of each solution:
Function URLs, cannot be used with API Gateway, always public
Asynchronous invocation
Response streaming
Lambda extensions
Custom runtime
Complexity
Easier to implement
Easiest to implement
The most complex solution to implement as it requires interacting with the extensions API and a dedicated thread
Medium as it interacts with the runtime API
Deployment
Need two artifacts: the synchronous function and the asynchronous function
A single deployment artifact that contains all code
A single deployment artifact that contains all code
A single deployment artifact, requires packaging all needed runtime files
Cost
Most expensive as it incurs additional invocation cost as well as the overall duration of both functions is higher than having it in one
Least expensive
Least expensive
Least expensive
Starting the async task
Before returning from handler
Anytime during the handler invocation
Anytime during the handler invocation
After returning the response to the client, unless you use a dedicated thread
Limitations
Payload sent to the asynchronous function cannot exceed 256 KB
Only supported with Node.js and custom runtimes. Requires Lambda Function URLs, cannot be used with API Gateway, always public
–
–
Additional benefits
Better decoupling between synchronous and asynchronous code
Ability to send response in stages. Supports payloads larger than 6 MB (at additional cost)
The asynchronous task runs in its own thread, which can reduce overall duration and cost
–
Retries in case of failure in async code
Managed by the Lambda service
Responsibility of the developer
Responsibility of the developer
Responsibility of the developer
Choosing the right approach depends on your use case. If you write your function in Node.js and you invoke it using Lambda Function URLs, use response streaming. This is the easiest way to implement, and it is the most cost effective.
If there is a chance for a failure in the asynchronous task (for example, a database is not accessible), and you must ensure that the task completes, use the asynchronous Lambda invocation method. The Lambda service retries your asynchronous function until it succeeds. Eventually, if all retries fail, it invokes a Lambda destination so you can take action.
If you need a custom runtime because you need to use a programming language that Lambda does not natively support, use the custom runtime option. Otherwise, use the Lambda extensions option. It is more complex to implement, but it is cost effective. This allows you to package the code in a single artifact and start processing the asynchronous task before you send the response to the client.
For more serverless learning resources, visit Serverless Land.
Data governance is a key enabler for teams adopting a data-driven culture and operational model to drive innovation with data. Amazon DataZone is a fully managed data management service that makes it faster and easier for customers to catalog, discover, share, and govern data stored across Amazon Web Services (AWS), on premises, and on third-party sources. It also makes it easier for engineers, data scientists, product managers, analysts, and business users to access data throughout an organization to discover, use, and collaborate to derive data-driven insights.
Amazon DataZone allows you to simply and securely govern end-to-end data assets stored in your Amazon Redshift data warehouses or data lakes cataloged with the AWS Glue data catalog. As you experience the benefits of consolidating your data governance strategy on top of Amazon DataZone, you may want to extend its coverage to new, diverse data repositories (either self-managed or as managed services) including relational databases, third-party data warehouses, analytic platforms and more.
This post explains how you can extend the governance capabilities of Amazon DataZone to data assets hosted in relational databases based on MySQL, PostgreSQL, Oracle or SQL Server engines. What’s covered in this post is already implemented and available in the Guidance for Connecting Data Products with Amazon DataZone solution, published in the AWS Solutions Library. This solution was built using the AWS Cloud Development Kit (AWS CDK) and was designed to be easy to set up in any AWS environment. It is based on a serverless stack for cost-effectiveness and simplicity and follows the best practices in the AWS Well-Architected-Framework.
Self-service analytics experience in Amazon DataZone
In Amazon DataZone, data producers populate the business data catalog with data assets from data sources such as the AWS Glue data catalog and Amazon Redshift. They also enrich their assets with business context to make them accessible to the consumers.
After the data asset is available in the Amazon DataZone business catalog, data consumers such as analysts and data scientists can search and access this data by requesting subscriptions. When the request is approved, Amazon DataZone can automatically provision access to the managed data asset by managing permissions in AWS Lake Formation or Amazon Redshift so that the data consumer can start querying the data using tools such as Amazon Athena or Amazon Redshift. Note that a managed data asset is an asset for which Amazon DataZone can manage permissions. It includes those stored in Amazon Simple Storage Service (Amazon S3) data lakes (and cataloged in the AWS Glue data catalog) or Amazon Redshift.
As you’ll see next, when working with relational databases, most of the experience described above will remain the same because Amazon DataZone provides a set features and integrations that data producers and consumers can use with a consistent experience, even when working with additional data sources. However, there are some additional tasks that need to be accounted for to achieve a frictionless experience, which will be addressed later in this post.
The following diagram illustrates a high-level overview of the flow of actions when a data producer and consumer collaborate around a data asset stored in a relational database using Amazon DataZone.
Figure 1: Flow of actions for self-service analytics around data assets stored in relational databases
First, the data producer needs to capture and catalog the technical metadata of the data asset.
The AWS Glue data catalog can be used to store metadata from a variety of data assets, like those stored in relational databases, including their schema, connection details, and more. It offers AWS Glue connections and AWS Glue crawlers as a means to capture the data asset’s metadata easily from their source database and keep it up to date. Later in this post, we’ll introduce how the “Guidance for Connecting Data Products with Amazon DataZone” solution can help data producers easily deploy and run AWS Glue connections and crawlers to capture technical metadata.
Second, the data producer needs to consolidate the data asset’s metadata in the business catalog and enrich it with business metadata. The producer also needs to manage and publish the data asset so it’s discoverable throughout the organization.
Amazon DataZone provides built-in data sources that allow you to easily fetch metadata (such as table name, column name, or data types) of assets in the AWS Glue data catalog into Amazon DataZone’s business catalog. You can also include data quality details thanks to the integration with AWS Glue Data Quality or external data quality solutions. Amazon DataZone also provides metadata forms and generative artificial intelligence (generative AI) driven suggestions to simplify the enrichment of data assets’ metadata with business context. Finally, the Amazon DataZone data portal helps you manage and publish your data assets.
Third, a data consumer needs to subscribe to the data asset published by the producer. To do so, the data consumer will submit a subscription request that, once approved by the producer, triggers a mechanism that automatically provisions read access to the consumer without moving or duplicating data.
In Amazon DataZone, data assets stored in relational databases are considered unmanaged data assets, which means that Amazon DataZone will not be able to manage permissions to them on the customer’s behalf. This is where the “Guidance for Connecting Data Products with Amazon DataZone” solution also comes in handy because it deploys the required mechanism to provision access automatically when subscriptions are approved. You’ll learn how the solution does this later in this post.
Finally, the data consumer needs to access the subscribed data once access has been provisioned. Depending on the use case, consumers would like to use SQL-based engines to run exploratory analysis, business intelligence (BI) tools to build dashboards for decision-making, or data science tools for machine learning (ML) development.
Amazon DataZone provides blueprints to give options for consuming data and provides default ones for Amazon Athena and Amazon Redshift, with more to come soon. Amazon Athena connectors is a good way to run one-time queries on top of relational databases. Later in this post we’ll introduce how the “Guidance for Connecting Data Products with Amazon DataZone” solution can help data consumers deploy Amazon Athena connectors and become a platform to deploy custom tools for data consumers.
Solution’s core components
Now that we have covered what the self-service analytics experience looks like when working with data assets stored in relational databases, let’s review at a high level the core components of the “Guidance for Connecting Data Products with Amazon DataZone” solution.
You’ll be able to identify where some of the core components fit in the flow of actions described in the last section because they were developed to bring simplicity and automation for a frictionless experience. Other components, even though they are not directly tied to the experience, are as relevant since they take care of the prerequisites for the solution to work properly.
Figure 2: Solution’s core components
The toolkit component is a set of tools (in AWS Service Catalog) that producer and consumer teams can easily deploy and use, in a self-service fashion, to support some of the tasks described in the experience, such as the following.
As a data producer, capture metadata from data assets stored in relational databases into the AWS Glue data catalog by leveraging AWS Glue connectors and crawlers.
As a data consumer, query a subscribed data asset directly from its source database with Amazon Athena by deploying and using an Amazon Athena connector.
The workflows component is a set of automated workflows (orchestrated through AWS Step Functions) that will trigger automatically on certain Amazon DataZone events such as:
When a new Amazon DataZone data lake environment is successfully deployed so that its default capabilities are extended to support this solution’s toolkit.
When a subscription request is accepted by a data producer so that access is provisioned automatically for data assets stored in relational databases. This workflow is the mechanism that was referred to in the experience of the last section as the means to provision access to unmanaged data assets governed by Amazon DataZone.
When a subscription is revoked or canceled so that access is revoked automatically for data assets in relational databases.
When an existing Amazon DataZone environment deletion starts so that non default Amazon DataZone capabilities are removed.
The following table lists the multiple AWS services that the solution uses to provide an add-on for Amazon DataZone with the purpose of providing the core components described in this section.
Used to store database credentials as secrets. Each consumer environment with granted subscription to one or many data assets in the same relational database will have its own individual credentials (secret).
Used to provide a complementary toolkit for users (producers and consumers), so that they can provision products to execute tasks specific to their roles in a self-service manner.
Multiple components are used, such as the AWS Glue data catalog as the direct publishing source for Amazon DataZone business catalog and connectors and crawlers to connect on infer schemas from data assets stored in relational databases.
Used as one of the consumption mechanisms that allow users and teams to query data assets that they are subscribed to, either on top of Amazon S3 backed data lakes and relational databases.
Solution overview
Now let’s dive into the workflow that automatically provisions access to an approved subscription request (2b in the last section). Figure 3 outlines the AWS services involved in its execution. It also illustrates when the solution’s toolkit is used to simplify some of the tasks that producers and consumers need to perform before and after a subscription is requested and granted. If you’d like to learn more about other workflows in this solution, please refer to the implementation guide.
The architecture illustrates how the solution works in a multi-account environment, which is a common scenario. In a multi-account environment, the governance account will host the Amazon DataZone domain and the remaining accounts will be associated to it. The producer account hosts the subscription’s data asset and the consumer account hosts the environment subscribing to the data asset.
Figure 3 – Architecture for subscription grant workflow
Solution walkthrough
1. Capture data asset’s metadata
A data producer captures metadata of a data asset to be published from its data source into the AWS Glue catalog. This can be done by using AWS Glue connections and crawlers. To speed up the process, the solution includes a Producer Toolkit using the AWS Service Catalog to simplify the deployment of such resources by just filling out a form.
Once the data asset’s technical metadata is captured, the data producer will run a data source job in Amazon DataZone to publish it into the business catalog. In the Amazon DataZone portal, a consumer will discover the data asset and subsequently, subscribe to it when needed. Any subscription action will create a subscription request in Amazon DataZone.
2. Approve a subscription request
The data producer approves the incoming subscription request. An event is sent to Amazon EventBridge, where a rule deployed by the solution captures it and triggers an instance of the AWS Step Functions primary state machine in the governance account for each environment of the subscribing project.
3. Fulfill read-access in the relational database (producer account)
The primary state machine in the governance account triggers an instance of the AWS Step Functions secondary state machine in the producer account, which will run a set of AWS Lambda functions to:
Retrieve the subscription data asset’s metadata from the AWS Glue catalog, including the details required for connecting to the data source hosting the subscription’s data asset.
Connect to the data source hosting the subscription’s data asset, create credentials for the subscription’s target environment (if nonexistent) and grant read access to the subscription’s data asset.
Store the new data source credentials in an AWS Secrets Manager producer secret (if nonexistent) with a resource policy allowing read cross-account access to the environment’s associated consumer account.
Update tracking records in Amazon DynamoDB in the governance account.
4. Share access credentials to the subscribing environment (consumer account)
The primary state machine in the governance account triggers an instance of the AWS Step Functions secondary state machine in the consumer account, which will run a set of AWS Lambda functions to:
Retrieve connection credentials from the producer secret in the producer account through cross-account access, then copy the credentials into a new consumer secret (if nonexistent) in AWS Secrets Manager local to the consumer account.
Update tracking records in Amazon DynamoDB in the governance account.
5. Access the subscribed data
The data consumer uses the consumer secret to connect to that data source and query the subscribed data asset using any preferred means.
To speed up the process, the solution includes a consumer toolkit using the AWS Service Catalog to simplify the deployment of such resources by just filling out a form. Current scope for this toolkit includes a tool that deploys an Amazon Athena connector for a corresponding MySQL, PostgreSQL, Oracle, or SQL Server data source. However, it could be extended to support other tools on top of AWS Glue, Amazon EMR, Amazon SageMaker, Amazon Quicksight, or other AWS services, and keep the same simple-to-deploy experience.
Conclusion
In this post we went through how teams can extend the governance of Amazon DataZone to cover relational databases, including those with MySQL, Postgres, Oracle, and SQL Server engines. Now, teams are one step further in unifying their data governance strategy in Amazon DataZone to deliver self-service analytics across their organizations for all of their data.
As a final thought, the solution explained in this post introduces a replicable pattern that can be extended to other relational databases. The pattern is based on access grants through environment-specific credentials that are shared as secrets in AWS Secrets Manager. For data sources with different authentication and authorization methods, the solution can be extended to provide the required means to grant access to them (such as through AWS Identity and Access Management (IAM) roles and policies). We encourage teams to experiment with this approach as well.
How to get started
With the “Guidance for Connecting Data Products with Amazon DataZone” solution, you have multiple resources to learn more, test it, and make it your own.
You can learn more on the AWS Solutions Library solutions page. You can download the source code from GitHub and follow the README file to learn more of its underlying components and how to set it up and deploy it in a single or multi-account environment. You can also use it to learn how to think of costs when using the solution. Finally, it explains how best practices from the AWS Well-Architected Framework were included in the solution.
You can follow the solution’s hands-on lab either with the help of the AWS Solutions Architect team or on your own. The lab will take you through the entire workflow described in this post for each of the supported database engines (MySQL, PostgreSQL, Oracle, and SQL Server). We encourage you to start here before trying the solution in your own testing environments and your own sample datasets. Once you have full clarity on how to set up and use the solution, you can test it with your workloads and even customize it to make it your own.
The implementation guide is an asset for customers eager to customize or extend the solution to their specific challenges and needs. It provides an in-depth description of the code repository structure and the solution’s underlying components, as well as all the details to understand the mechanisms used to track all subscriptions handled by the solution.
About the authors
Jose Romero is a Senior Solutions Architect for Startups at AWS, based in Austin, TX, US. He is passionate about helping customers architect modern platforms at scale for data, AI, and ML. As a former senior architect with AWS Professional Services, he enjoys building and sharing solutions for common complex problems so that customers can accelerate their cloud journey and adopt best practices. Connect with him on LinkedIn..
Leonardo Gómez is a Principal Big Data / ETL Solutions Architect at AWS, based in Florida, US. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs. Connect with him on LinkedIn.
One of GitHub’s core values is Diverse and Inclusive. It is a guiding thought for how we operate, reminding us that GitHub serves a developer community that spans a wide range of geography and ability.
Putting diversity and inclusivity into practice means incorporating a wide range of perspectives into our work. To that point, disability and accessibility are an integral part of our efforts.
This consideration has been instrumental in crafting resilient, accessible components at GitHub. These components, in turn, help to guarantee that our experiences work regardless how they are interacted with.
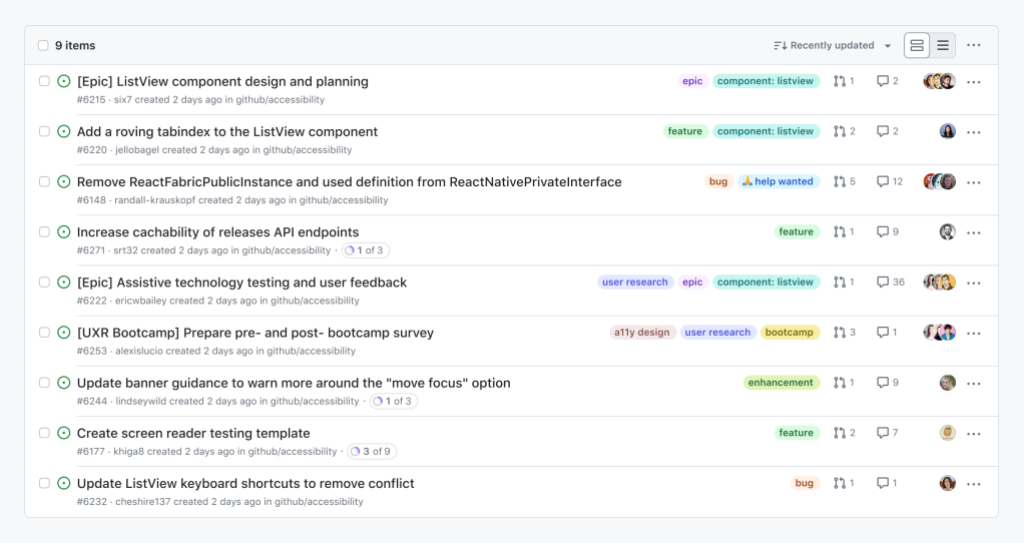
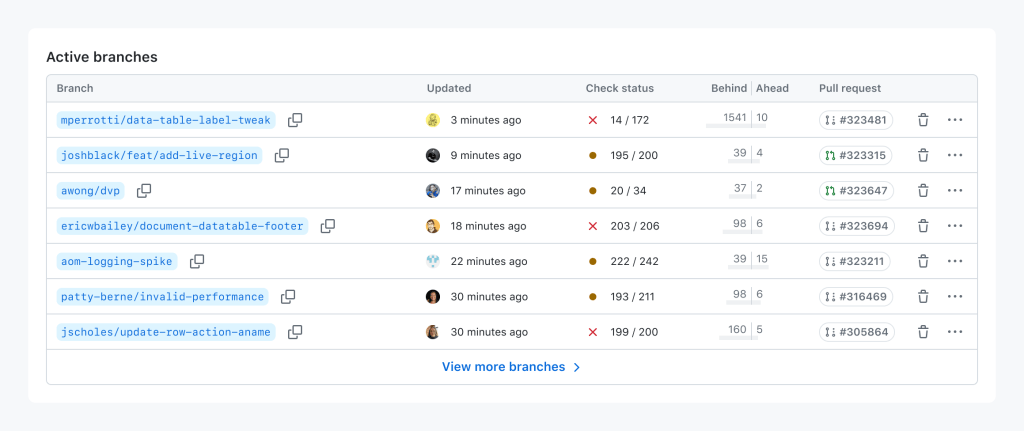
Using GitHub should be efficient and intuitive, regardless of your device, circumstance, or ability. To that point, we have been working on improving the accessibility of our lists of issues and pull requests, as well as our information tables.
Our list of issues and pull requests are some of the most high-traffic experiences we have on GitHub. For many, it is the “homepage” of their open source projects, a jumping off point for conducting and managing work.
Our tables help to communicate, and facilitate taking action with confidence on complicated information relationships. These experiences are workhorses, helping to communicate information about branches, repositories, secrets, attestations, configurations, internal documentation, etc.
Nothing about us without us
Before we discuss the particulars of these updates, I would like to call attention to the most important aspect of the work: direct participation of, and input from daily assistive technology users.
Disabled people’s direct involvement in the inception, design, and development stages is indispensable. It’s crucial for us to go beyond compliance and weave these practices into the core of our organization. Only by doing so can we create genuinely inclusive experiences.
With this context established, we can now talk about how this process manifests in component work.
Improvements we’re making to lists of issues and pull requests
Lists of issues and pull requests will continue to support methods of navigation via assistive technology that you may already be familiar with—making experiences consistent and predictable is a huge and often overlooked aspect of the work.
In addition, these lists will soon be updated to also have:
A dedicated subheading for quickly navigating to the list itself.
Primer-derived tables help provide consistency and predictability. This is important for expected table navigation, but also applies for other table-related experiences, such as loading content, sorting and pagination requests, and bulk and row-level actions.
At the time of this blog post’s publishing, there are 75 bespoke tables that have been replaced with the Primer component, spread across all of GitHub.
The reason for this quiet success has been due entirely to close collaboration with both our disabled partners and our design system experts. This collaboration helped to ensure:
The new table experiences were seamlessly integrated.
Doing so, improved and enhanced the underlying assistive technology experience.
Progress over perfection
Meryl K. Evans’ Progress Over Perfection philosophy heavily influenced how we approached this work.
Accessibility is never done. Part of our dedication to this work is understanding that it will grow and change to meet the needs of the people who rely on it. This means making positive, iterative change based on feedback from the community GitHub serves.
More to come
Tables will continue to be updated, and the lists should be released publicly soon. Beyond that, we’re excited about the changes we’re making to improve GitHub’s accessibility. This includes both our services and also our internal culture.
We hope that these components, and the process that led to their creation, help you as both part of our developer community and as people who build the world’s software.
In this post, we explore how Amazon Web Services (AWS) customers can use Amazon Security Lake to efficiently collect, query, and centralize logs on AWS. We also discuss new use cases for Security Lake, such as applying generative AI to Security Lake data for threat hunting and incident response, and we share the latest service enhancements and developments from our growing landscape. Security Lake centralizes security data from AWS environments, software as a service (SaaS) providers, and on-premises and cloud sources into a purpose-built data lake that is stored in your AWS account. Using Open Cybersecurity Schema Framework (OCSF) support, Security Lake normalizes and combines security data from AWS and a broad range of third-party data sources. This helps provide your security team with the ability to investigate and respond to security events and analyze possible threats within your environment, which can facilitate timely responses and help to improve your security across multicloud and hybrid environments.
One year ago, AWS embarked on a mission driven by the growing customer need to revolutionize how security professionals centralize, optimize, normalize, and analyze their security data. As we celebrate the one-year general availability milestone of Amazon Security Lake, we’re excited to reflect on the journey and showcase how customers are using the service, yielding both productivity and cost benefits, while maintaining ownership of their data.
In this section, we highlight how some of our customers have found the most value with Security Lake and how you can use Security Lake in your organization.
Simplify the centralization of security data management across hybrid environments to enhance security analytics
Many customers use Security Lake to gather and analyze security data from various sources, including AWS, multicloud, and on-premises systems. By centralizing this data in a single location, organizations can streamline data collection and analysis, help eliminate data silos, and improve cross-environment analysis. This enhanced visibility and efficiency allows security teams to respond more effectively to security events. With Security Lake, customers simplify data gathering and reduce the burden of data retention and extract, transform, and load (ETL) processes with key AWS data sources.
For example, Interpublic Group (IPG), an advertising company, uses Security Lake to gain a comprehensive, organization-wide grasp of their security posture across hybrid environments. Watch this video from re:Inforce 2023 to understand how IPG streamlined their security operations.
Before adopting Security Lake, the IPG team had to work through the challenge of managing diverse log data sources. This involved translating and transforming the data, as well as reconciling complex elements like IP addresses. However, with the implementation of Security Lake, IPG was able to access previously unavailable log sources. This enabled them to consolidate and effectively analyze security-related data. The use of Security Lake has empowered IPG to gain comprehensive insight into their security landscape, resulting in a significant improvement in their overall security posture.
“We can achieve a more complete, organization-wide understanding of our security posture across hybrid environments. We could quickly create a security data lake that centralized security-related data from AWS and third-party sources,” — Troy Wilkinson, Global CISO at Interpublic Group
Streamline incident investigation and reduce mean time to respond
As organizations expand their cloud presence, they need to gather information from diverse sources. Security Lake automates the centralization of security data from AWS environments and third-party logging sources, including firewall logs, storage security, and threat intelligence signals. This removes the need for custom, one-off security consolidation pipelines. The centralized data in Security Lake streamlines security investigations, making security management and investigations simpler. Whether you’re in operations or a security analyst, dealing with multiple applications and scattered data can be tough. Security Lake makes it simpler by centralizing the data, reducing the need for scattered systems. Plus, with data stored in your Amazon Simple Storage Service (Amazon S3) account, Security Lake lets you store a lot of historical data, which helps when looking back for patterns or anomalies indicative of security issues.
For example, SEEK, an Australian online employment marketplace, uses Security Lake to streamline incident investigations and reduce mean time to respond (MTTR). Watch this video from re:Invent 2023 to understand how SEEK improved its incident response. Prior to using Security Lake, SEEK had to rely on a legacy VPC Flow Logs system to identify possible indicators of compromise, which took a long time. With Security Lake, the company was able to more quickly identify a host in one of their accounts that was communicating with a malicious IP. Now, Security Lake has provided SEEK with swift access to comprehensive data across diverse environments, facilitating forensic investigations and enabling them scale their security operations better.
Optimize your log retention strategy
Security Lake simplifies data management for customers who need to store large volumes of security logs to meet compliance requirements. It provides customizable retention settings and automated storage tiering to optimize storage costs and security analytics. It automatically partitions and converts incoming security data into a storage and query-efficient Apache Parquet format. Security Lake uses the Apache Iceberg open table format to enhance query performance for your security analytics. Customers can now choose which logs to keep for compliance reasons, which logs to send to their analytics solutions for further analysis, and which logs to query in place for incident investigation use cases. Security Lake helps customers to retain logs that were previously unfeasible to store and to extend storage beyond their typical retention policy, within their security information and event management (SIEM) system.
Figure 2 shows a section of the Security Lake activation page, which presents users with options to set rollup AWS Regions and storage classes.
Figure 2: Security Lake activation page with options to select a roll-up Region and set storage classes
For example, Carrier, an intelligent climate and energy solutions company, relies on Security Lake to strengthen its security and governance practices. By using Security Lake, Carrier can adhere to compliance with industry standards and regulations, safeguarding its operations and optimizing its log retention.
“Amazon Security Lake simplifies the process of ingesting and analyzing all our security-related log and findings data into a single data lake, strengthening our enterprise-level security and governance practices. This streamlined approach has enhanced our ability to identify and address potential issues within our environment more effectively, enabling us to proactively implement mitigations based on insights derived from the service,” — Justin McDowell, Associate Director for Enterprise Cloud Services at Carrier
Proactive threat and vulnerability detection
Security Lake helps customers identify potential threats and vulnerabilities earlier in the development process by facilitating the correlation of security events across different data sources, allowing security analysts to identify complex attack patterns more effectively. This proactive approach shifts the responsibility for maintaining secure coding and infrastructure to earlier phases, enhancing overall security posture. Security Lake can also optimize security operations by automating safeguard protocols and involving engineering teams in decision-making, validation, and remediation processes. Also, by seamlessly integrating with security orchestration tools, Security Lake can help expedite responses to security incidents and preemptively help mitigate vulnerabilities before exploitation occurs.
For example, SPH Media, a Singapore media company, uses Security Lake to get better visibility into security activity across their organization, enabling proactive identification of potential threats and vulnerabilities.
Security Lake and generative AI for threat hunting and incident response practices
Centralizing security-related data allows organizations to efficiently analyze behaviors from systems and users across their environments, providing deeper insight into potential risks. With Security Lake, customers can centralize their security logs and have them stored in a standardized format using OCSF. OCSF implements a well-documented schema maintained at schema.ocsf.io, which generative AI can use to contextualize the structured data within Security Lake tables. Security personnel can then ask questions of the data using familiar security investigation terminology rather than needing data analytics skills to translate an otherwise simple question into complex SQL (Structured Query Language) queries. Building upon the previous processes, Amazon Bedrock then takes an organization’s natural language incident response playbooks and converts them into a sequence of queries capable of automating what would otherwise be manual investigation tasks.
“Organizations can benefit from using Amazon Security Lake to centralize and manage security data with the OCSF and Apache Parquet format. It simplifies the integration of disparate security log sources and findings, reducing complexity and cost. By applying generative AI to Security Lake data, SecOps can streamline security investigations, facilitate timely responses, and enhance their overall security,” — Phil Bues, Research Manager, Cloud Security at IDC
Enhance incident response workflow with contextual alerts
Incident responders commonly deal with a high volume of automatically generated alerts from their IT environment. Initially, the response team members sift through numerous log sources to uncover relevant details about affected resources and the causes of alerts, which adds time to the remediation process. This manual process also consumes valuable analyst time, particularly if the alert turns out to be a false positive.
To reduce this burden on incident responders, customers can use generative AI to perform initial investigations and generate human-readable context from alerts. Amazon QuickSight Q is a generative AI–powered assistant that can answer questions, provide summaries, generate content, and securely complete tasks based on data and information in your enterprise systems. Incident responders can now combine these capabilities with data in Amazon Security Lake to begin their investigation and build detailed dashboards in minutes. This allows them to visually identify resources and activities that could potentially trigger alerts, giving incident responders a head start in their response efforts. The approach can also be used to validate alert information against alternative sources, enabling faster identification of false positives and allowing responders to focus on genuine security incidents.
As natural language processing (NLP) models evolve they can also interpret incident response playbooks, often written in a human-readable, step-by-step format. Amazon Q Apps will enable the incident responder to use natural language to quickly and securely build their own generative AI playbooks to automate their tasks. This automation can streamline incident response tasks such as creating tickets in the relevant ticketing system, logging bugs in the version control system that hosts application code, and tagging resources as non-compliant if they fail to adhere to the organization’s IT security policy.
Incident investigation with automatic dashboard generation
By using Amazon QuickSight Q and data in Security Lake, incident responders can now generate customized visuals based on the specific characteristics and context of the incident they are investigating. The incident response team can start with a generic investigative question and automatically produce dashboards without writing SQL queries or learning the complexities of how to build a dashboard.
After building a topic in Amazon QuickSight Q. The investigator can either ask their own question or utilize the AI generated questions that Q has provided. In the example shown in Figure 3, the incident responder suspects a potential security incident and is seeking more information about Create or Update API calls in their environment, by asking ” I’m looking for what accounts ran an update or create api call in the last week, can you display the API Operation?
Figure 3: AI Generated visual to begin the investigation
This automatically generated dashboard can be saved for later and from this dashboard the investigator can just focus on one account with a simple right click and get more information about the API calls performed by a single account. as shown in Figure 4.
Figure 4: Investigating API calls for a single account
Using the centralized security data in Amazon Security Lake and Amazon QuickSight Q, incident responders can jump-start investigations and rapidly validate potential threats without having to write complex queries or manually construct dashboards.
Updates since GA launch
Security Lake makes it simpler to analyze security data, gain a more comprehensive understanding of security across your entire organization, and improve the protection of your workloads, applications, and data. Since the general availability release in 2023, we have made various updates to the service. It’s now available in 17 AWS Regions globally. To assist you in evaluating your current and future Security Lake usage and cost estimates, we’ve introduced a new usage page. If you’re currently in a 15-day free trial, your trial usage can serve as a reference for estimating post-trial costs. Accessing Security Lake usage and projected costs is as simple as logging into the Security Lake console.
We have released an integration with Amazon Detective that enables querying and retrieving logs stored in Security Lake. Detective begins pulling raw logs from Security Lake related to AWS CloudTrail management events and Amazon VPC Flow Logs. Security Lake enhances analytics performance with support for OCSF 1.1.0 and Apache Iceberg. Also, Security Lake has integrated several OCSF mapping enhancements, including OCSF Observables, and has adopted the latest version of the OCSF datetime profile for improved usability. Security Lake seamlessly centralizes and normalizes Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, simplifying monitoring and investigation of potential suspicious activities in your Amazon EKS clusters, without requiring additional setup or affecting existing configurations.
The global team of experts in the AWS Professional Services organization can help customers realize their desired business outcomes with AWS. Our teams of data architects and security engineers collaborate with customer security, IT, and business leaders to develop enterprise solutions.
The AWS ProServe Amazon Security Lake Assessment offering is a complimentary workshop for customers. It entails a two-week interactive assessment, delving deep into customer use cases and creating a program roadmap to implement Security Lake alongside a suite of analytics solutions. Through a series of technical and strategic discussions, the AWS ProServe team analyzes use cases for data storage, security, search, visualization, analytics, AI/ML, and generative AI. The team then recommends a target future state architecture to achieve the customer’s security operations goals. At the end of the workshop, customers receive a draft architecture and implementation plan, along with infrastructure cost estimates, training, and other technical recommendations.
Summary
In this post, we showcased how customers use Security Lake to collect, query, and centralize logs on AWS. We discussed new applications for Security Lake and generative AI for threat hunting and incident response. We invite you to discover the benefits of using Security Lake through our 15-day free trial and share your feedback. To help you in getting started and building your first security data lake, we offer a range of resources including an infographic, eBook, demo videos, and webinars. There are many different use cases for Security Lake that can be tailored to suit your AWS environment. Join us at AWS re:Inforce 2024, our annual cloud security event, for more insights and firsthand experiences of how Security Lake can help you centralize, normalize, and optimize your security data.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
As a developer, you can now use your company’s single sign-on credentials to sign in to Bedrock Studio and start experimenting. You can build applications using a wide array of top performing models, evaluate, and share your generative AI apps within Bedrock Studio. The user interface guides you through various steps to help improve a model’s responses. You can experiment with model settings, and securely integrate your company data sources, tools, and APIs, and set guardrails. You can collaborate with team members to ideate, experiment, and refine your generative AI applications—all without requiring advanced machine learning (ML) expertise or AWS Management Console access.
As an Amazon Web Services (AWS) administrator, you can be confident that developers will only have access to the features provided by Bedrock Studio, and won’t have broader access to AWS infrastructure and services.
Now, let me show you how to get started with Amazon Bedrock Studio.
Get started with Amazon Bedrock Studio As an AWS administrator, you first need to create an Amazon Bedrock Studio workspace, then select and add users you want to give access to the workspace. Once the workspace is created, you can share the workspace URL with the respective users. Users with access privileges can sign in to the workspace using single sign-on, create projects within their workspace, and start building generative AI applications.
Create Amazon Bedrock Studio workspace Navigate to the Amazon Bedrock console and choose Bedrock Studio on the bottom left pane.
Before creating a workspace, you need to configure and secure the single sign-on integration with your identity provider (IdP) using the AWS IAM Identity Center. For detailed instructions on how to configure various IdPs, such as AWS Directory Service for Microsoft Active Directory, Microsoft Entra ID, or Okta, check out the AWS IAM Identity Center User Guide. For this demo, I configured user access with the default IAM Identity Center directory.
If you want, you can also select default generative AI models and embedding models for the workspace. Once you’re done, choose Create.
Next, select the created workspace.
Then, choose User management and Add users or groups to select the users you want to give access to this workspace.
Back in the Overview tab, you can now copy the Bedrock Studio URL and share it with your users.
Build generative AI applications using Amazon Bedrock Studio As a builder, you can now navigate to the provided Bedrock Studio URL and sign in with your single sign-on user credentials. Welcome to Amazon Bedrock Studio! Let me show you how to choose from industry leading FMs, bring your own data, use functions to make API calls, and safeguard your applications using guardrails.
Choose from multiple industry leading FMs By choosing Explore, you can start selecting available FMs and explore the models using natural language prompts.
If you choose Build, you can start building generative AI applications in a playground mode, experiment with model configurations, iterate on system prompts to define the behavior of your application, and prototype new features.
Bring your own data With Bedrock Studio, you can securely bring your own data to customize your application by providing a single file or by selecting a knowledge base created in Amazon Bedrock.
Use functions to make API calls and make model responses more relevant A function call allows the FM to dynamically access and incorporate external data or capabilities when responding to a prompt. The model determines which function it needs to call based on an OpenAPI schema that you provide.
Functions enable a model to include information in its response that it doesn’t have direct access to or prior knowledge of. For example, a function could allow the model to retrieve and include the current weather conditions in its response, even though the model itself doesn’t have that information stored.
Safeguard your applications using Guardrails for Amazon Bedrock You can create guardrails to promote safe interactions between users and your generative AI applications by implementing safeguards customized to your use cases and responsible AI policies.
When you create applications in Amazon Bedrock Studio, the corresponding managed resources such as knowledge bases, agents, and guardrails are automatically deployed in your AWS account. You can use the Amazon Bedrock API to access those resources in downstream applications.
Here’s a short demo video of Amazon Bedrock Studio created by my colleague Banjo Obayomi.
Join the preview Amazon Bedrock Studio is available today in public preview in AWS Regions US East (N. Virginia) and US West (Oregon). To learn more, visit the Amazon Bedrock Studio page and User Guide.
Give Amazon Bedrock Studio a try today and let us know what you think! Send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS contacts, and engage with the generative AI builder community at community.aws.
The
systemd project is preparing for a new release.
Version 256-rc1 was released
on April 25 with a large number of changes and new features. Most of the
changes relate to security, easier configuration, unprivileged access to system
resources, or all three of these. Users of systemd will find setting up
containers — even without root access — much simpler and more secure.
This attack has been feasible for over two decades:
Researchers have devised an attack against nearly all virtual private network applications that forces them to send and receive some or all traffic outside of the encrypted tunnel designed to protect it from snooping or tampering.
TunnelVision, as the researchers have named their attack, largely negates the entire purpose and selling point of VPNs, which is to encapsulate incoming and outgoing Internet traffic in an encrypted tunnel and to cloak the user’s IP address. The researchers believe it affects all VPN applications when they’re connected to a hostile network and that there are no ways to prevent such attacks except when the user’s VPN runs on Linux or Android. They also said their attack technique may have been possible since 2002 and may already have been discovered and used in the wild since then.
[…]
The attack works by manipulating the DHCP server that allocates IP addresses to devices trying to connect to the local network. A setting known as option 121 allows the DHCP server to override default routing rules that send VPN traffic through a local IP address that initiates the encrypted tunnel. By using option 121 to route VPN traffic through the DHCP server, the attack diverts the data to the DHCP server itself.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
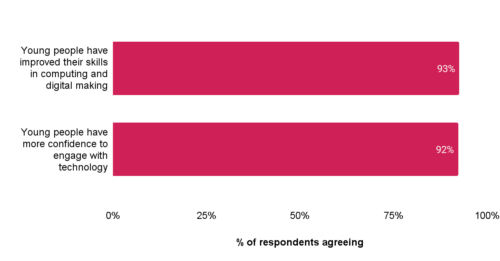



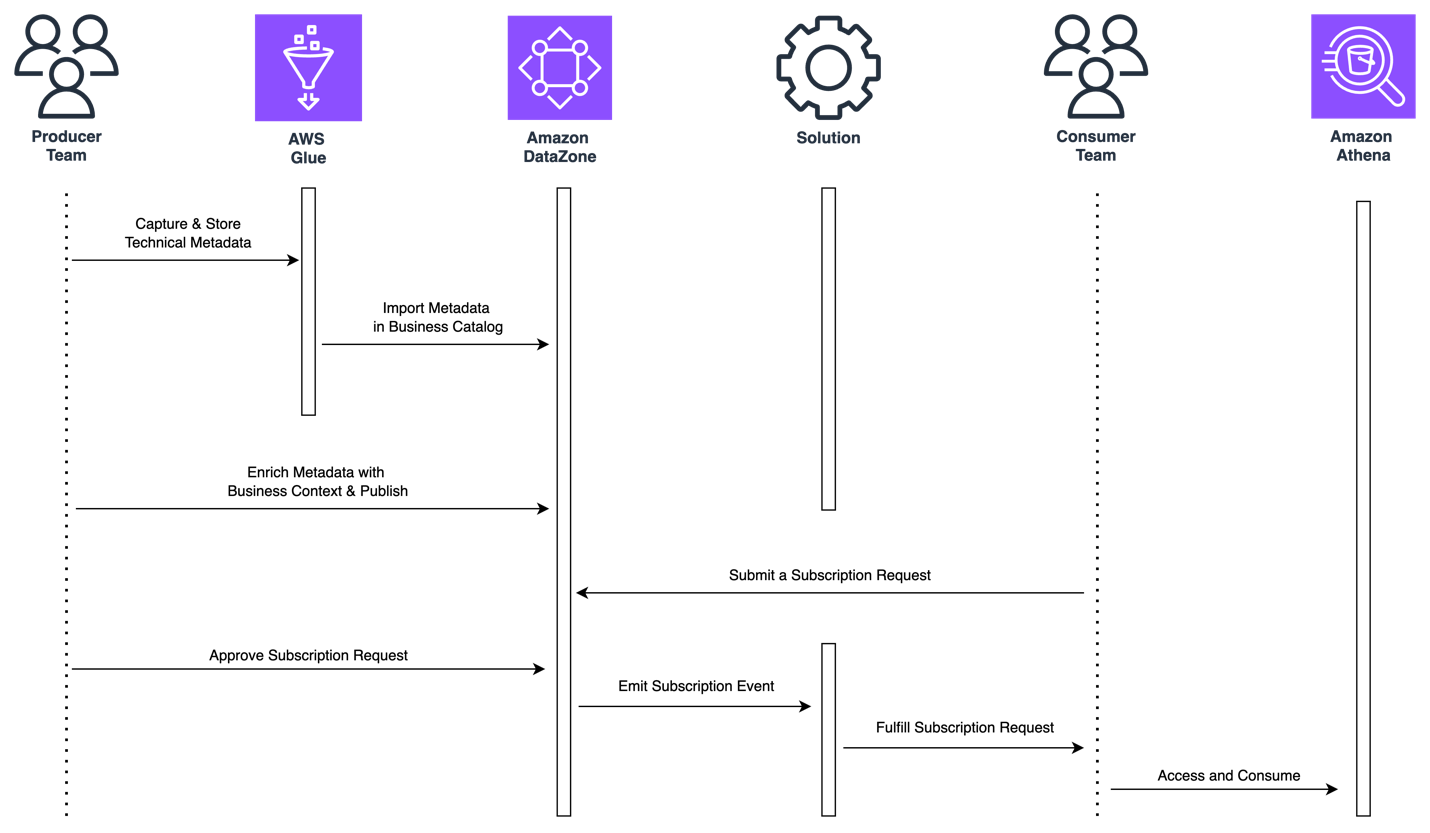


 Jose Romero is a Senior Solutions Architect for Startups at AWS, based in Austin, TX, US. He is passionate about helping customers architect modern platforms at scale for data, AI, and ML. As a former senior architect with AWS Professional Services, he enjoys building and sharing solutions for common complex problems so that customers can accelerate their cloud journey and adopt best practices. Connect with him on
 Leonardo Gómez is a Principal Big Data / ETL Solutions Architect at AWS, based in Florida, US. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs. Connect with him on