Tag Archives: AI

Partnering with Black Forest Labs to bring FLUX.2 [dev] to Workers AI

Post Syndicated from Michelle Chen original https://blog.cloudflare.com/flux-2-workers-ai/

In recent months, we’ve seen a leap forward for closed-source image generation models with the rise of Google’s Nano Banana and OpenAI image generation models. Today, we’re happy to share that a new open-weight contender is back with the launch of Black Forest Lab’s FLUX.2 [dev] and available to run on Cloudflare’s inference platform, Workers AI. You can read more about this new model in detail on BFL’s blog post about their new model launch here.

We have been huge fans of Black Forest Lab’s FLUX image models since their earliest versions. Our hosted version of FLUX.1 [schnell] is one of the most popular models in our catalog for its photorealistic outputs and high-fidelity generations. When the time came to host the licensed version of their new model, we jumped at the opportunity. The FLUX.2 model takes all the best features of FLUX.1 and amps it up, generating even more realistic, grounded images with added customization support like JSON prompting.

Our Workers AI hosted version of FLUX.2 has some specific patterns, like using multipart form data to support input images (up to 4 512×512 images), and output images up to 4 megapixels. The multipart form data format allows users to send us multiple image inputs alongside the typical model parameters. Check out our developer docs changelog announcement to understand how to use the FLUX.2 model.

What makes FLUX.2 special? Physical world grounding, digital world assets, and multi-language support

The FLUX.2 model has a more robust understanding of the physical world, allowing you to turn abstract concepts into photorealistic reality. It excels at generating realistic image details and consistently delivers accurate hands, faces, fabrics, logos, and small objects that are often missed by other models. Its knowledge of the physical world also generates life-like lighting, angles and depth perception.


Figure 1. Image generated with FLUX.2 featuring accurate lighting, shadows, reflections and depth perception at a café in Paris.

This high-fidelity output makes it ideal for applications requiring superior image quality, such as creative photography, e-commerce product shots, marketing visuals, and interior design. Because it can understand context, tone, and trends, the model allows you to create engaging and editorial-quality digital assets from short prompts.

Aside from the physical world, the model is also able to generate high-quality digital assets such as designing landing pages or generating detailed infographics (see below for example). It’s also able to understand multiple languages naturally, so combining these two features – we can get a beautiful landing page in French from a French prompt.

Générer une page web visuellement immersive pour un service de promenade de chiens. L'image principale doit dominer l'écran, montrant un chien exubérant courant dans un parc ensoleillé, avec des touches de vert vif (#2ECC71) intégrées subtilement dans le feuillage ou les accessoires du chien. Minimiser le texte pour un impact visuel maximal.

Character consistency – solving for stochastic drift

FLUX.2 offers multi-reference editing with state-of-the-art character consistency, ensuring identities, products, and styles remain consistent for tasks. In the world of generative AI, getting a high-quality image is easy. However, getting the exact same character or product twice has always been the hard part. This is a phenomenon known as “stochastic drift”, where generated images drift away from the original source material.


Figure 2. Stochastic drift infographic (generated on FLUX.2)

One of FLUX.2’s breakthroughs is multi-reference image inputs designed to solve this consistency challenge. You’ll have the ability to change the background, lighting, or pose of an image without accidentally changing the face of your model or the design of your product. You can also reference other images or combine multiple images together to create something new. 

In code, Workers AI supports multi-reference images (up to 4) with a multipart form-data upload. The image inputs are binary images and output is a base64 encoded image:

curl --request POST \
  --url 'https://api.cloudflare.com/client/v4/accounts/{ACCOUNT}/ai/run/@cf/black-forest-labs/flux-2-dev' \
  --header 'Authorization: Bearer {TOKEN}' \
  --header 'Content-Type: multipart/form-data' \
  --form 'prompt=take the subject of image 2 and style it like image 1' \
  --form input_image_0=@/Users/johndoe/Desktop/icedoutkeanu.png \
  --form input_image_1=@/Users/johndoe/Desktop/me.png \
  --form steps=25
  --form width=1024
  --form height=1024

We also support this through the Workers AI Binding:

const image = await fetch("http://image-url");
const form = new FormData();
 
const image_blob = await streamToBlob(image.body, "image/png");
form.append('input_image_0', image_blob)
form.append('prompt', 'a sunset with the dog in the original image')
 
const resp = await env.AI.run("@cf/black-forest-labs/flux-2-dev", {
    multipart: {
        body: form,
        contentType: "multipart/form-data"
    }
})

Built for real world use cases

The newest image model signifies a shift towards functional business use cases, moving beyond simple image quality improvements. FLUX.2 enables you to:

  • Create Ad Variations: Generate 50 different advertisements using the exact same actor, without their face morphing between frames.

  • Trust Your Product Shots: Drop your product on a model, or into a beach scene, a city street, or a studio table. The environment changes, but your product stays accurate.

  • Build Dynamic Editorials: Produce a full fashion spread where the model looks identical in every single shot, regardless of the angle.


Figure 3. Combining the oversized hoodie and sweatpant ad photo (generated with FLUX.2) with Cloudflare’s logo to create product renderings with consistent faces, fabrics, and scenery. **Note: we prompted for white Cloudflare font as well instead of the original black font. 

Granular controls — JSON prompting, HEX codes and more!

The FLUX.2 model makes another advancement by allowing users to control small details in images through tools like JSON prompting and specifying specific hex codes.

For example, you could send this JSON as a prompt (as part of the multipart form input) and the resulting image follows the prompt exactly:


{
  "scene": "A bustling, neon-lit futuristic street market on an alien planet, rain slicking the metal ground",
  "subjects": [
    {
      "type": "Cyberpunk bounty hunter",
      "description": "Female, wearing black matte armor with glowing blue trim, holding a deactivated energy rifle, helmet under her arm, rain dripping off her synthetic hair",
      "pose": "Standing with a casual but watchful stance, leaning slightly against a glowing vendor stall",
      "position": "foreground"
    },
    {
      "type": "Merchant bot",
      "description": "Small, rusted, three-legged drone with multiple blinking red optical sensors, selling glowing synthetic fruit from a tray attached to its chassis",
      "pose": "Hovering slightly, offering an item to the viewer",
      "position": "midground"
    }
  ],
  "style": "noir sci-fi digital painting",
  "color_palette": [
    "deep indigo",
    "electric blue",
    "acid green"
  ],
  "lighting": "Low-key, dramatic, with primary light sources coming from neon signs and street lamps reflecting off wet surfaces",
  "mood": "Gritty, tense, and atmospheric",
  "background": "Towering, dark skyscrapers disappearing into the fog, with advertisements scrolling across their surfaces, flying vehicles (spinners) visible in the distance",
  "composition": "dynamic off-center",
  "camera": {
    "angle": "eye level",
    "distance": "medium close-up",
    "focus": "sharp on subject",
    "lens": "35mm",
    "f-number": "f/1.4",
    "ISO": 400
  },
  "effects": [
    "heavy rain effect",
    "subtle film grain",
    "neon light reflections",
    "mild chromatic aberration"
  ]
}

To take it further, we can ask the model to recolor the accent lighting to a Cloudflare orange by giving it a specific hex code like #F48120.


Try it out today!

The newest FLUX.2 [dev] model is now available on Workers AI — you can get started with the model through our developer docs or test it out on our multimodal playground.

Accelerate investigations with AWS Security Incident Response AI-powered capabilities

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/accelerate-investigations-with-aws-security-incident-response-ai-powered-capabilities/

If you’ve ever spent hours manually digging through AWS CloudTrail logs, checking AWS Identity and Access Management (IAM) permissions, and piecing together the timeline of a security event, you understand the time investment required for incident investigation. Today, we’re excited to announce the addition of AI-powered investigation capabilities to AWS Security Incident Response that automate this evidence gathering and analysis work.

AWS Security Incident Response helps you prepare for, respond to, and recover from security events faster and more effectively. The service combines automated security finding monitoring and triage, containment, and now AI-powered investigation capabilities with 24/7 direct access to the AWS Customer Incident Response Team (CIRT).

While investigating a suspicious API call or unusual network activity, scoping and validation require querying multiple data sources, correlating timestamps, identifying related events, and building a complete picture of what happened. Security operations center (SOC) analysts devote a significant amount of time to each investigation, with roughly half of that effort spent manually gathering and piecing together evidence from various tools and complex logs. This manual effort can delay your analysis and response.

AWS is introducing an investigative agent to Security Incident Response, changing this paradigm and adding layers of efficiency. The investigative agent helps you reduce the time required to validate and respond to potential security events. When a case for a security concern is created, either by you or proactively by Security Incident Response, the investigative agent asks clarifying questions to make sure it understands the full context of the potential security event. It then automatically gathers evidence from CloudTrail events, IAM configurations, and Amazon Elastic Compute Cloud (Amazon EC2) instance details and even analyzes cost usage patterns. Within minutes, it correlates the evidence, identifies patterns, and presents you with a clear summary.

How it works in practice

Before diving into an example, let’s paint a clear picture of where the investigative agent lives, how it’s accessed, and its purpose and function. The investigative agent is built directly into Security Incident Response and is automatically available when you create a case. Its purpose is to act as your first responder—gathering evidence, correlating data across AWS services, and building a comprehensive timeline of events so you can quickly move from detection to recovery.

For example: you discover that AWS credentials for an IAM user in your account were exposed in a public GitHub repository. You need to understand what actions were taken with those credentials and properly scope the potential security event, including lateral movement and reconnaissance operations. You need to identify persistence mechanisms that might have been created and determine the appropriate containment steps. To get started, you create a case in the Security Incident Response console and describe the situation.

Here’s where the agent’s approach differs from traditional automation: it asks clarifying questions first. When were the credentials first exposed? What’s the IAM user name? Have you already rotated the credentials? Which AWS account is affected?

This interactive step gathers the appropriate details and metadata before it starts gathering evidence. Specifically, you’re not stuck with generic results—the investigation is tailored to your specific concern.

After the agent has what it needs, it investigates. It looks up CloudTrail events to see what API calls were made using the compromised credentials, pulls IAM user and role details to check what permissions were granted, identifies new IAM users or roles that were created, checks EC2 instance information if compute resources were launched, and analyzes cost and usage patterns for unusual resource consumption. Instead of you querying each AWS service, the agent orchestrates this automatically.

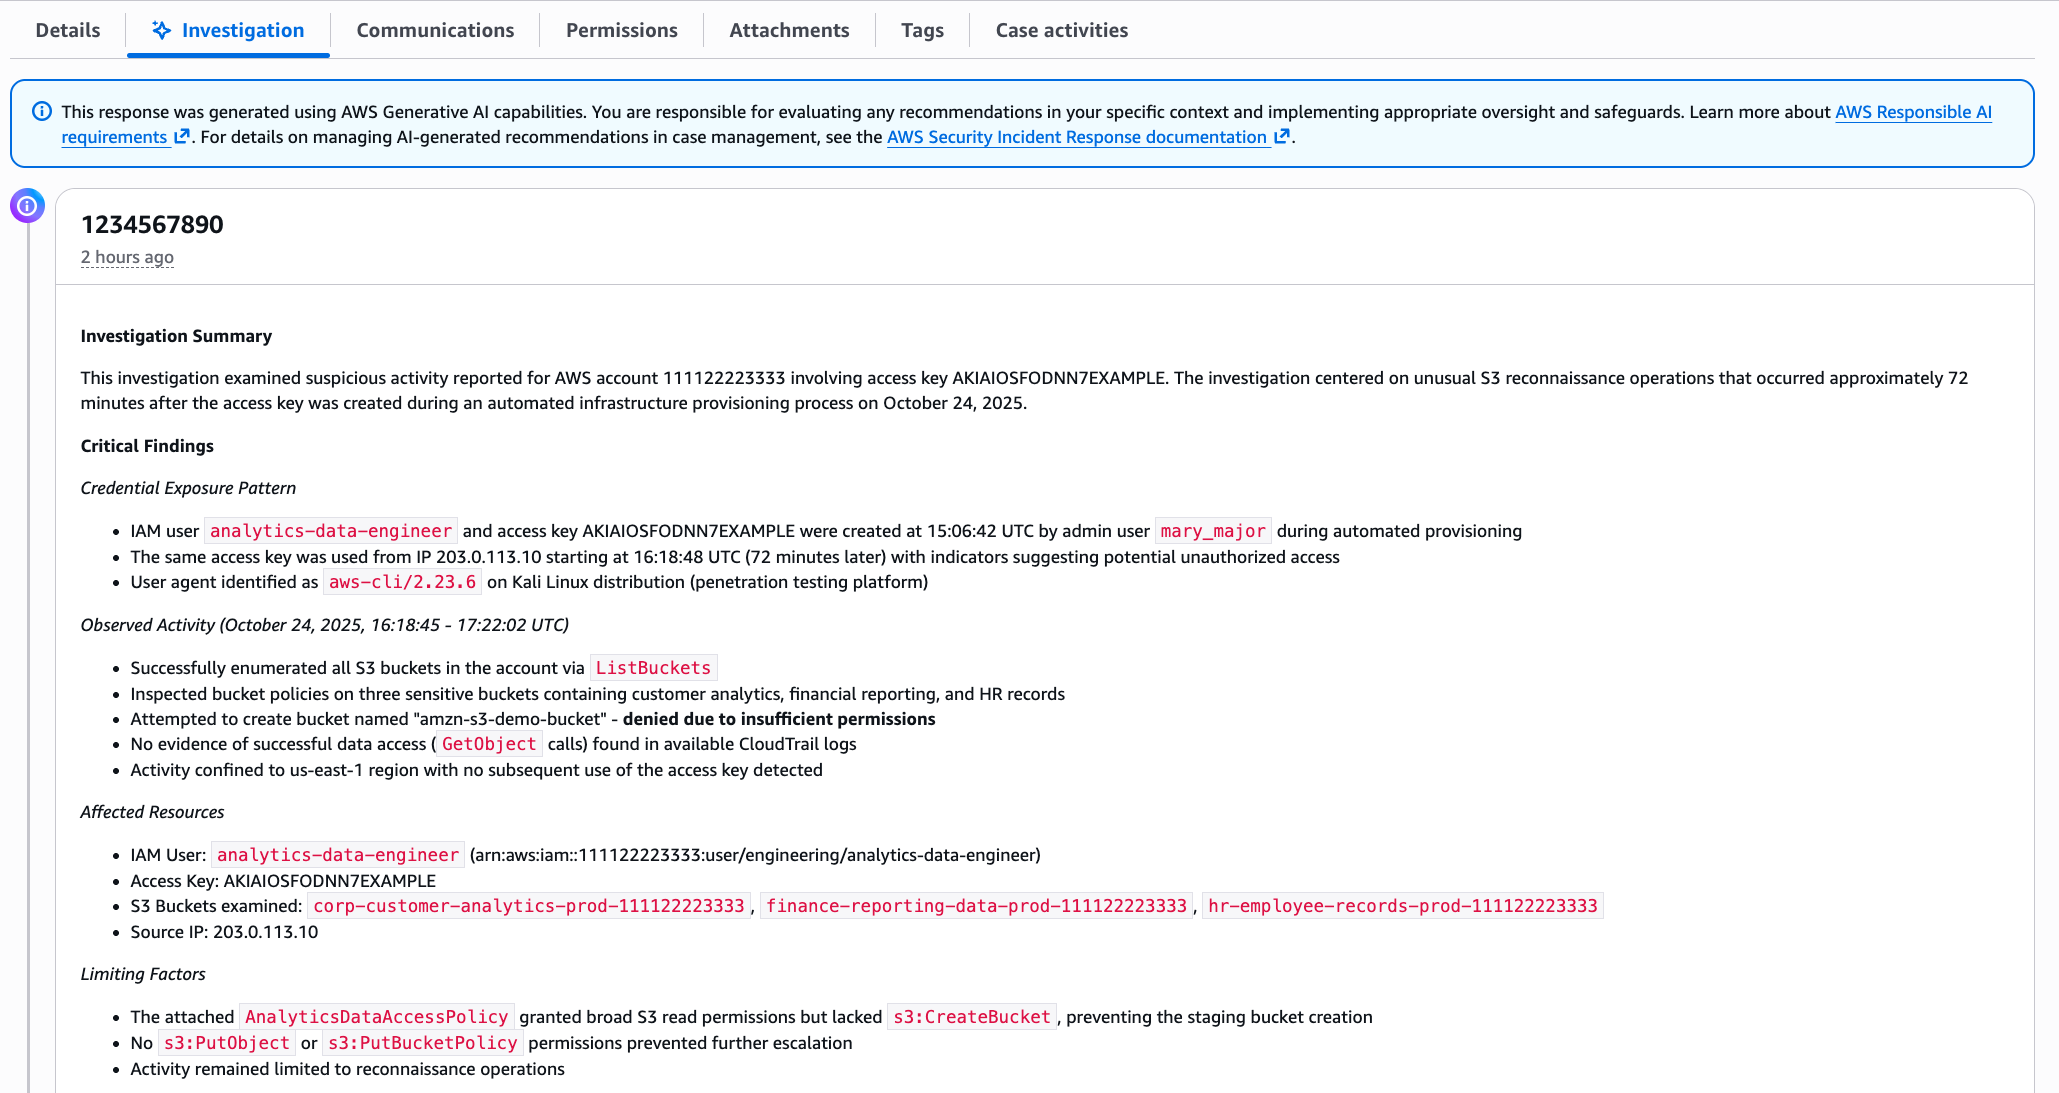
Within minutes, you get a summary, as shown in the following figure. The investigation summary includes a high-level summary and critical findings, which include the credential exposure pattern, observed activity and the timeframe, affected resources, and limiting factors.

This response was generated using AWS Generative AI capabilities. You are responsible for evaluating any recommendations in your specific context and implementing appropriate oversight and safeguards. Learn more about AWS Responsible AI requirements.

Note: The preceding example is representative output. Exact formatting will vary depending on findings.

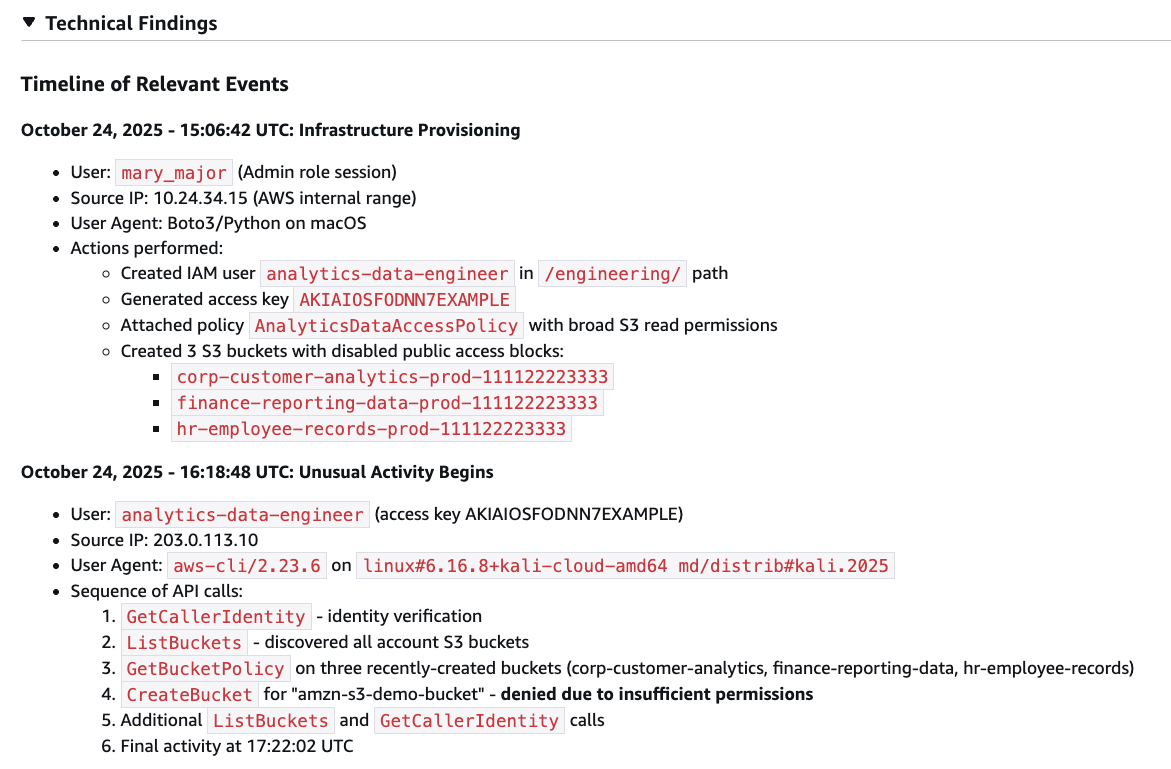
The investigation summary includes various tabs for detailed information, such as technical findings with an events timeline, as shown in the following figure:

Figure 2 – Security event timeline

Figure 2 – Security event timeline

When seconds count, this transparency is paramount to a quick, high-fidelity, and accurate response—especially if you need to escalate to the AWS CIRT, a dedicated group of AWS security experts, or explain your findings to leadership, creating a single lens for stakeholders to view the incident.

When the investigation is complete, you have a high-resolution picture of what happened and can make informed decisions about containment, eradication, and recovery. For the preceding exposed credentials scenario, you might need to:

  • Delete the compromised access keys
  • Remove the newly created IAM role
  • Terminate the unauthorized EC2 instances
  • Review and revert associated IAM policy changes
  • Check for additional access keys created for other users.

When you engage with the CIRT, they can provide additional guidance on containment strategies based on the evidence the agent gathered.

What this means for your security operations

The leaked credentials scenario shows what the agent can do for a single incident. But the bigger impact is on how you operate day-to-day:

  • You spend less time on evidence collection. The investigative agent automates the most time-consuming part of investigations—gathering and correlating evidence from multiple sources. Instead of spending an hour on manual log analysis, you can spend most of that time on making containment decisions and preventing recurrence.
  • You can investigate in plain language. The investigative agent uses natural language processing (NLP), which you can use to describe what you’re investigating in plain language, such as unusual API calls from IP address X or data access from terminated employee’s credentials, and the agent translates that into the technical queries needed. You don’t need to be an expert in AWS log formats or know the exact syntax for querying CloudTrail.
  • You get a foundation for high-fidelity and accurate investigations. The investigative agent handles the initial investigation—gathering evidence, identifying patterns, and providing a comprehensive summary. If your case requires deeper analysis or you need guidance on complex scenarios, you can engage with the AWS CIRT, who can immediately build on the work the agent has already done, speeding up their response time. They see the same evidence and timeline, so they can focus on advanced threat analysis and containment strategies rather than starting from scratch.

Getting started

If you already have Security Incident Response enabled, the AI-powered investigation capabilities are available now—no additional configuration needed. Create your next security case and the agent will start working automatically.

If you’re new to Security Incident Response, here’s how to set it up:

  1. Enable Security Incident Response through your AWS Organizations management account. This takes a few minutes through the AWS Management Console and provides coverage across your accounts.
  2. Create a case. Describe what you’re investigating; you can do this through the Security Incident Response console or an API, or set up automatic case creation from Amazon GuardDuty or AWS Security Hub alerts.
  3. Review the analysis. The agent presents its findings through the Security Incident Response console, or you can access them through your existing ticketing systems such as Jira or ServiceNow.

The investigative agent uses the AWS Support service-linked role to gather information from your AWS resources. This role is automatically created when you set up your AWS account and provides the necessary access for Support tools to query CloudTrail events, IAM configurations, EC2 details, and cost data. Actions taken by the agent are logged in CloudTrail for full auditability.

The investigative agent is included at no additional cost with Security Incident Response, which now offers metered pricing with a free tier covering your first 10,000 findings ingested per month. Beyond that, findings are billed at rates that decrease with volume. With this consumption-based approach, you can scale your security incident response capabilities as your needs grow.

How it fits with existing tools

Security Incident Response cases can be created by customers or proactively by the service. The investigative agent is automatically triggered when a new case is created, and cases can be managed through the console, API, or Amazon EventBridge integrations.

You can use EventBridge to build automated workflows that route security events from GuardDuty, Security Hub, and Security Incident Response itself to create cases and initiate response plans, enabling end-to-end detection-to-investigation pipelines. Before the investigative agent begins its work, the service’s auto-triage system monitors and filters security findings from GuardDuty and third-party security tools through Security Hub. It uses customer-specific information, such as known IP addresses and IAM entities, to filter findings based on expected behavior, reducing alert volume while escalating alerts that require immediate attention. This means the investigative agent focuses on alerts that actually need investigation.

Conclusion

In this post, I showed you how the new investigative agent in AWS Security Incident Response automates evidence gathering and analysis, reducing the time required to investigate security events from hours to minutes. The agent asks clarifying questions to understand your specific concern, automatically queries multiple AWS data sources, correlates evidence, and presents you with a comprehensive timeline and summary while maintaining full transparency and auditability.

With the addition of the investigative agent, Security Incident Response customers now get the speed and efficiency of AI-powered automation, backed by the expertise and oversight of AWS security experts when needed.

The AI-powered investigation capabilities are available today in all commercial AWS Regions where Security Incident Response operates. To learn more about pricing and features, or to get started, visit the AWS Security Incident Response product page.

If you have feedback about this post, submit comments in the Comments section below.

Daniel Begimher

Daniel Begimher

Daniel is a Senior Security Engineer in Global Services Security, specializing in cloud security, application security, and incident response. He co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community, holds all AWS certifications, and authored Automated Security Helper (ASH), an open source code scanning tool.

AI as Cyberattacker

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/ai-as-cyberattacker.html

From Anthropic:

In mid-September 2025, we detected suspicious activity that later investigation determined to be a highly sophisticated espionage campaign. The attackers used AI’s “agentic” capabilities to an unprecedented degree­—using AI not just as an advisor, but to execute the cyberattacks themselves.

The threat actor—­whom we assess with high confidence was a Chinese state-sponsored group—­manipulated our Claude Code tool into attempting infiltration into roughly thirty global targets and succeeded in a small number of cases. The operation targeted large tech companies, financial institutions, chemical manufacturing companies, and government agencies. We believe this is the first documented case of a large-scale cyberattack executed without substantial human intervention.

[…]

The attack relied on several features of AI models that did not exist, or were in much more nascent form, just a year ago:

  1. Intelligence. Models’ general levels of capability have increased to the point that they can follow complex instructions and understand context in ways that make very sophisticated tasks possible. Not only that, but several of their well-developed specific skills—in particular, software coding­—lend themselves to being used in cyberattacks.
  2. Agency. Models can act as agents—­that is, they can run in loops where they take autonomous actions, chain together tasks, and make decisions with only minimal, occasional human input.
  3. Tools. Models have access to a wide array of software tools (often via the open standard Model Context Protocol). They can now search the web, retrieve data, and perform many other actions that were previously the sole domain of human operators. In the case of cyberattacks, the tools might include password crackers, network scanners, and other security-related software.

AI and Voter Engagement

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/ai-and-voter-engagement.html

Social media has been a familiar, even mundane, part of life for nearly two decades. It can be easy to forget it was not always that way.

In 2008, social media was just emerging into the mainstream. Facebook reached 100 million users that summer. And a singular candidate was integrating social media into his political campaign: Barack Obama. His campaign’s use of social media was so bracingly innovative, so impactful, that it was viewed by journalist David Talbot and others as the strategy that enabled the first term Senator to win the White House.

Over the past few years, a new technology has become mainstream: AI. But still, no candidate has unlocked AI’s potential to revolutionize political campaigns. Americans have three more years to wait before casting their ballots in another Presidential election, but we can look at the 2026 midterms and examples from around the globe for signs of how that breakthrough might occur.

How Obama Did It

Rereading the contemporaneous reflections of the New York Times’ late media critic, David Carr, on Obama’s campaign reminds us of just how new social media felt in 2008. Carr positions it within a now-familiar lineage of revolutionary communications technologies from newspapers to radio to television to the internet.

The Obama campaign and administration demonstrated that social media was different from those earlier communications technologies, including the pre-social internet. Yes, increasing numbers of voters were getting their news from the internet, and content about the then-Senator sometimes made a splash by going viral. But those were still broadcast communications: one voice reaching many. Obama found ways to connect voters to each other.

In describing what social media revolutionized in campaigning, Carr quotes campaign vendor Blue State Digital’s Thomas Gensemer: “People will continue to expect a conversation, a two-way relationship that is a give and take.”

The Obama team made some earnest efforts to realize this vision. His transition team launched change.gov, the website where the campaign collected a “Citizen’s Briefing Book” of public comment. Later, his administration built We the People, an online petitioning platform.

But the lasting legacy of Obama’s 2008 campaign, as political scientists Hahrie Han and Elizabeth McKenna chronicled, was pioneering online “relational organizing.” This technique enlisted individuals as organizers to activate their friends in a self-perpetuating web of relationships.

Perhaps because of the Obama campaign’s close association with the method, relational organizing has been touted repeatedly as the linchpin of Democratic campaigns: in 2020, 2024, and today. But research by non-partisan groups like Turnout Nation and right-aligned groups like the Center for Campaign Innovation has also empirically validated the effectiveness of the technique for inspiring voter turnout within connected groups.

The Facebook of 2008 worked well for relational organizing. It gave users tools to connect and promote ideas to the people they know: college classmates, neighbors, friends from work or church. But the nature of social networking has changed since then.

For the past decade, according to Pew Research, Facebook use has stalled and lagged behind YouTube, while Reddit and TikTok have surged. These platforms are less useful for relational organizing, at least in the traditional sense. YouTube is organized more like broadcast television, where content creators produce content disseminated on their own channels in a largely one-way communication to their fans. Reddit gathers users worldwide in forums (subreddits) organized primarily on topical interest. The endless feed of TikTok’s “For You” page disseminates engaging content with little ideological or social commonality. None of these platforms shares the essential feature of Facebook c. 2008: an organizational structure that emphasizes direct connection to people that users have direct social influence over.

AI and Relational Organizing

Ideas and messages might spread virally through modern social channels, but they are not where you convince your friends to show up at a campaign rally. Today’s platforms are spaces for political hobbyism, where you express your political feelings and see others express theirs.

Relational organizing works when one person’s action inspires others to do this same. That’s inherently a chain of human-to-human connection. If my AI assistant inspires your AI assistant, no human notices and one’s vote changes. But key steps in the human chain can be assisted by AI. Tell your phone’s AI assistant to craft a personal message to one friend—or a hundred—and it can do it.

So if a campaign hits you at the right time with the right message, they might persuade you to task your AI assistant to ask your friends to donate or volunteer. The result can be something more than a form letter; it could be automatically drafted based on the entirety of your email or text correspondence with that friend. It could include references to your discussions of recent events, or past campaigns, or shared personal experiences. It could sound as authentic as if you’d written it from the heart, but scaled to everyone in your address book.

Research suggests that AI can generate and perform written political messaging about as well as humans. AI will surely play a tactical role in the 2026 midterm campaigns, and some candidates may even use it for relational organizing in this way.

(Artificial) Identity Politics

For AI to be truly transformative of politics, it must change the way campaigns work. And we are starting to see that in the US.

The earliest uses of AI in American political campaigns are, to be polite, uninspiring. Candidates viewed them as just another tool to optimize an endless stream of email and text message appeals, to ramp up political vitriol, to harvest data on voters and donors, or merely as a stunt.

Of course, we have seen the rampant production and spread of AI-powered deepfakes and misinformation. This is already impacting the key 2026 Senate races, which are likely to attract hundreds of millions of dollars in financing. Roy Cooper, Democratic candidate for US Senate from North Carolina, and Abdul El-Sayed, Democratic candidate for Senate from Michigan, were both targeted by viral deepfake attacks in recent months. This may reflect a growing trend in Donald Trump’s Republican party in the use of AI-generated imagery to build up GOP candidates and assail the opposition.

And yet, in the global elections of 2024, AI was used more memetically than deceptively. So far, conservative and far right parties seem to have adopted this most aggressively. The ongoing rise of Germany’s far-right populist AfD party has been credited to its use of AI to generate nostalgic and evocative (and, to many, offensive) campaign images, videos, and music and, seemingly as a result, they have dominated TikTok. Because most social platforms’ algorithms are tuned to reward media that generates an emotional response, this counts as a double use of AI: to generate content and to manipulate its distribution.

AI can also be used to generate politically useful, though artificial, identities. These identities can fulfill different roles than humans in campaigning and governance because they have differentiated traits. They can’t be imprisoned for speaking out against the state, can be positioned (legitimately or not) as unsusceptible to bribery, and can be forced to show up when humans will not.

In Venezuela, journalists have turned to AI avatars—artificial newsreaders—to report anonymously on issues that would otherwise elicit government retaliation. Albania recently “appointed” an AI to a ministerial post responsible for procurement, claiming that it would be less vulnerable to bribery than a human. In Virginia, both in 2024 and again this year, candidates have used AI avatars as artificial stand-ins for opponents that refused to debate them.

And yet, none of these examples, whether positive or negative, pursue the promise of the Obama campaign: to make voter engagement a “two-way conversation” on a massive scale.

The closest so far to fulfilling that vision anywhere in the world may be Japan’s new political party, Team Mirai. It started in 2024, when an independent Tokyo gubernatorial candidate, Anno Takahiro, used an AI avatar on YouTube to respond to 8,600 constituent questions over a seventeen-day continuous livestream. He collated hundreds of comments on his campaign manifesto into a revised policy platform. While he didn’t win his race, he shot up to a fifth place finish among a record 56 candidates.

Anno was RECENTLY elected to the upper house of the federal legislature as the founder of a new party with a 100 day plan to bring his vision of a “public listening AI” to the whole country. In the early stages of that plan, they’ve invested their share of Japan’s 32 billion yen in party grants—public subsidies for political parties—to hire engineers building digital civic infrastructure for Japan. They’ve already created platforms to provide transparency for party expenditures, and to use AI to make legislation in the Diet easy, and are meeting with engineers from US-based Jigsaw Labs (a Google company) to learn from international examples of how AI can be used to power participatory democracy.

Team Mirai has yet to prove that it can get a second member elected to the Japanese Diet, let alone to win substantial power, but they’re innovating and demonstrating new ways of using AI to give people a way to participate in politics that we believe is likely to spread.

Organizing with AI

AI could be used in the US in similar ways. Following American federalism’s longstanding model of “laboratories of democracy,” we expect the most aggressive campaign innovation to happen at the state and local level.

D.C. Mayor Muriel Bowser is partnering with MIT and Stanford labs to use the AI-based tool deliberation.io to capture wide scale public feedback in city policymaking about AI. Her administration said that using AI in this process allows “the District to better solicit public input to ensure a broad range of perspectives, identify common ground, and cultivate solutions that align with the public interest.”

It remains to be seen how central this will become to Bowser’s expected re-election campaign in 2026, but the technology has legitimate potential to be a prominent part of a broader program to rebuild trust in government. This is a trail blazed by Taiwan a decade ago. The vTaiwan initiative showed how digital tools like Pol.is, which uses machine learning to make sense of real time constituent feedback, can scale participation in democratic processes and radically improve trust in government. Similar AI listening processes have been used in Kentucky, France, and Germany.

Even if campaigns like Bowser’s don’t adopt this kind of AI-facilitated listening and dialog, expect it to be an increasingly prominent part of American public debate. Through a partnership with Jigsaw, Scott Rasmussen’s Napolitan Institute will use AI to elicit and synthesize the views of at least five Americans from every Congressional district in a project called “We the People.” Timed to coincide with the country’s 250th anniversary in 2026, expect the results to be promoted during the heat of the midterm campaign and to stoke interest in this kind of AI-assisted political sensemaking.

In the year where we celebrate the American republic’s semiquincentennial and continue a decade-long debate about whether or not Donald Trump and the Republican party remade in his image is fighting for the interests of the working class, representation will be on the ballot in 2026. Midterm election candidates will look for any way they can get an edge. For all the risks it poses to democracy, AI presents a real opportunity, too, for politicians to engage voters en masse while factoring their input into their platform and message. Technology isn’t going to turn an uninspiring candidate into Barack Obama, but it gives any aspirant to office the capability to try to realize the promise that swept him into office.

This essay was written with Nathan E. Sanders, and originally appeared in The Fulcrum.

Replicate is joining Cloudflare

Post Syndicated from Rita Kozlov original https://blog.cloudflare.com/replicate-joins-cloudflare/

We have some big news to share today: Replicate, the leading platform for running AI models, is joining Cloudflare.

We first started talking to Replicate because we shared a lot in common beyond just a passion for bright color palettes. Our mission for Cloudflare’s Workers developer platform has been to make building and deploying full-stack applications as easy as possible. Meanwhile, Replicate has been on a similar mission to make deploying AI models as easy as writing a single line of code. And we realized we could build something even better together by integrating the Replicate platform into Cloudflare directly.

We are excited to share this news and even more excited for what it will mean for customers. Bringing Replicate’s tools into Cloudflare will continue to make our Developer Platform the best place on the Internet to build and deploy any AI or agentic workflow.

What does this mean for you? 

Before we spend more time talking about the future of AI, we want to answer the questions that are top of mind for Replicate and Cloudflare users. In short: 

For existing Replicate users: Your APIs and workflows will continue to work without interruption. You will soon benefit from the added performance and reliability of Cloudflare’s global network.

For existing Workers AI users: Get ready for a massive expansion of the model catalog and the new ability to run fine-tunes and custom models directly on Workers AI.

Now – let’s get back into why we’re so excited about our joint future.

The AI Revolution was not televised, but it started with open source

Before AI was AI, and the subject of every conversation, it was known for decades as “machine learning”. It was a specialized, almost academic field. Progress was steady but siloed, with breakthroughs happening inside a few large, well-funded research labs. The models were monolithic, the data was proprietary, and the tools were inaccessible to most developers. Everything changed when the culture of open-source collaboration — the same force that built the modern Internet — collided with machine learning, as researchers and companies began publishing not just their papers, but their model weights and code.

This ignited an incredible explosion of innovation. The pace of change in just the past few years has been staggering; what was state-of-the-art 18 months ago (or sometimes it feels like just days ago) is now the baseline. This acceleration is most visible in generative AI. 

We went from uncanny, blurry curiosities to photorealistic image generation in what felt like the blink of an eye. Open source models like Stable Diffusion unlocked immediate creativity for developers, and that was just the beginning. If you take a look at Replicate’s model catalog today, you’ll see thousands of image models of almost every flavor, each iterating on the previous. 

This happened not just with image models, but video, audio, language models and more…. 

But this incredible, community-driven progress creates a massive practical challenge: How do you actually run these models? Every new model has different dependencies, requires specific GPU hardware (and enough of it), and needs a complex serving infrastructure to scale. Developers found themselves spending more time fighting with CUDA drivers and requirements.txt files than actually building their applications.

This is exactly the problem Replicate solved. They built a platform that abstracts away all that complexity (using their open-source tool Cog to package models into standard, reproducible containers), letting any developer or data scientist run even the most complex open-source models with a simple API call. 

Today, Replicate’s catalog spans more than 50,000 open-source models and fine-tuned models. While open source unlocked so many possibilities, Replicate’s toolset goes beyond that to make it possible for developers to access any models they need in one place. Period. With their marketplace, they also offer seamless access to leading proprietary models like GPT-5 and Claude Sonnet, all through the same unified API.

What’s worth noting is that Replicate didn’t just build an inference service; they built a community. So much innovation happens through being inspired by what others are doing, iterating on it, and making it better. Replicate has become the definitive hub for developers to discover, share, fine-tune, and experiment with the latest models in a public playground. 

Stronger together: the AI catalog meets the AI cloud

Coming back to the Workers Platform mission: Our goal all along has been to enable developers to build full-stack applications without having to burden themselves with infrastructure. And while that hasn’t changed, AI has changed the requirements of applications.

The types of applications developers are building are changing — three years ago, no one was building agents or creating AI-generated launch videos. Today they are. As a result, what they need and expect from the cloud, or the AI cloud, has changed too.

To meet the needs of developers, Cloudflare has been building the foundational pillars of the AI Cloud, designed to run inference at the edge, close to users. This isn’t just one product, but an entire stack:

  • Workers AI: Serverless GPU inference on our global network.

  • AI Gateway: A control plane for caching, rate-limiting, and observing any AI API.

  • Data Stack: Including Vectorize (our vector database) and R2 (for model and data storage).

  • Orchestration: Tools like AI Search (formerly Autorag), Agents, and Workflows to build complex, multi-step applications.

  • Foundation: All built on our core developer platform of Workers, Durable Objects, and the rest of our stack.

As we’ve been helping developers scale up their applications, Replicate has been on a similar mission — to make deploying AI models as easy as deploying code. This is where it all comes together. Replicate brings one of the industry’s largest and most vibrant model catalog and developer community. Cloudflare brings an incredibly performant global network and serverless inference platform. Together, we can deliver the best of both worlds: the most comprehensive selection of models, runnable on a fast, reliable, and affordable inference platform.

Our shared vision

For the community: the hub for AI exploration

The ability to share models, publish fine-tunes, collect stars, and experiment in the playground is the heart of the Replicate community. We will continue to invest in and grow this as the premier destination for AI discovery and experimentation, now supercharged by Cloudflare’s global network for an even faster, more responsive experience for everyone.

The future of inference: one platform, all models

Our vision is to bring the best of both platforms together. We will bring the entire Replicate catalog — all 50,000+ models and fine-tunes — to Workers AI. This gives you the ultimate choice: run models in Replicate’s flexible environment or on Cloudflare’s serverless platform, all from one place.

But we’re not just expanding the catalog. We are thrilled to announce that we will be bringing fine-tuning capabilities to Workers AI, powered by Replicate’s deep expertise. We are also making Workers AI more flexible than ever. Soon, you’ll be able to bring your own custom models to our network. We’ll leverage Replicate’s expertise with Cog to make this process seamless, reproducible, and easy.

The AI Cloud: more than just inference

Running a model is just one piece of the puzzle. The real magic happens when you connect AI to your entire application. Imagine what you can build when Replicate’s massive catalog is deeply integrated with the entire Cloudflare developer platform: run a model and store the results directly in R2 or Vectorize; trigger inference from a Worker or Queue; use Durable Objects to manage state for an AI agent; or build real-time generative UI with WebRTC and WebSockets.

To manage all this, we will integrate our unified inference platform deeply with the AI Gateway, giving you a single control plane for observability, prompt management, A/B testing, and cost analytics across all your models, whether they’re running on Cloudflare, Replicate, or any other provider.

Welcome to the team!

We are incredibly excited to welcome the Replicate team to Cloudflare. Their passion for the developer community and their expertise in the AI ecosystem are unmatched. We can’t wait to build the future of AI together.

The Role of Humans in an AI-Powered World

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/the-role-of-humans-in-an-ai-powered-world.html

As AI capabilities grow, we must delineate the roles that should remain exclusively human. The line seems to be between fact-based decisions and judgment-based decisions.

For example, in a medical context, if an AI was demonstrably better at reading a test result and diagnosing cancer than a human, you would take the AI in a second. You want the more accurate tool. But justice is harder because justice is inherently a human quality in a way that “Is this tumor cancerous?” is not. That’s a fact-based question. “What’s the right thing to do here?” is a human-based question.

Chess provides a useful analogy for this evolution. For most of history, humans were best. Then, in the 1990s, Deep Blue beat the best human. For a while after that, a good human paired with a good computer could beat either one alone. But a few years ago, that changed again, and now the best computer simply wins. There will be an intermediate period for many applications where the human-AI combination is optimal, but eventually, for fact-based tasks, the best AI will likely surpass both.

The enduring role for humans lies in making judgments, especially when values come into conflict. What is the proper immigration policy? There is no single “right” answer; it’s a matter of feelings, values, and what we as a society hold dear. A lot of societal governance is about resolving conflicts between people’s rights—my right to play my music versus your right to have quiet. There’s no factual answer there. We can imagine machines will help; perhaps once we humans figure out the rules, the machines can do the implementing and kick the hard cases back to us. But the fundamental value judgments will likely remain our domain.

This essay originally appeared in IVY.

MLPerf Training v5.1 NVIDIA Dominates while AMD Has a Strong Showing and Cisco Silicon

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/mlperf-training-v5-1-nvidia-dominates-while-amd-has-a-strong-showing-and-cisco-silicon/

MLPerf Training v5.1 is out, with NVIDIA dominating. AMD showed up and performed well. Cisco Silicon One and MangoBoost DPUs made cameos

The post MLPerf Training v5.1 NVIDIA Dominates while AMD Has a Strong Showing and Cisco Silicon appeared first on ServeTheHome.

Prompt Injection in AI Browsers

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/prompt-injection-in-ai-browsers.html

This is why AIs are not ready to be personal assistants:

A new attack called ‘CometJacking’ exploits URL parameters to pass to Perplexity’s Comet AI browser hidden instructions that allow access to sensitive data from connected services, like email and calendar.

In a realistic scenario, no credentials or user interaction are required and a threat actor can leverage the attack by simply exposing a maliciously crafted URL to targeted users.

[…]

CometJacking is a prompt-injection attack where the query string processed by the Comet AI browser contains malicious instructions added using the ‘collection’ parameter of the URL.

LayerX researchers say that the prompt tells the agent to consult its memory and connected services instead of searching the web. As the AI tool is connected to various services, an attacker leveraging the CometJacking method could exfiltrate available data.

In their tests, the connected services and accessible data include Google Calendar invites and Gmail messages and the malicious prompt included instructions to encode the sensitive data in base64 and then exfiltrate them to an external endpoint.

According to the researchers, Comet followed the instructions and delivered the information to an external system controlled by the attacker, evading Perplexity’s checks.

I wrote previously:

Prompt injection isn’t just a minor security problem we need to deal with. It’s a fundamental property of current LLM technology. The systems have no ability to separate trusted commands from untrusted data, and there are an infinite number of prompt injection attacks with no way to block them as a class. We need some new fundamental science of LLMs before we can solve this.

Faking Receipts with AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/faking-receipts-with-ai.html

Over the past few decades, it’s become easier and easier to create fake receipts. Decades ago, it required special paper and printers—I remember a company in the UK advertising its services to people trying to cover up their affairs. Then, receipts became computerized, and faking them required some artistic skills to make the page look realistic.

Now, AI can do it all:

Several receipts shown to the FT by expense management platforms demonstrated the realistic nature of the images, which included wrinkles in paper, detailed itemization that matched real-life menus, and signatures.

[…]

The rise in these more realistic copies has led companies to turn to AI to help detect fake receipts, as most are too convincing to be found by human reviewers.

The software works by scanning receipts to check the metadata of the image to discover whether an AI platform created it. However, this can be easily removed by users taking a photo or a screenshot of the picture.

To combat this, it also considers other contextual information by examining details such as repetition in server names and times and broader information about the employee’s trip.

Yet another AI-powered security arms race.

Scientists Need a Positive Vision for AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/scientists-need-a-positive-vision-for-ai.html

For many in the research community, it’s gotten harder to be optimistic about the impacts of artificial intelligence.

As authoritarianism is rising around the world, AI-generated “slop” is overwhelming legitimate media, while AI-generated deepfakes are spreading misinformation and parroting extremist messages. AI is making warfare more precise and deadly amidst intransigent conflicts. AI companies are exploiting people in the global South who work as data labelers, and profiting from content creators worldwide by using their work without license or compensation. The industry is also affecting an already-roiling climate with its enormous energy demands.

Meanwhile, particularly in the United States, public investment in science seems to be redirected and concentrated on AI at the expense of other disciplines. And Big Tech companies are consolidating their control over the AI ecosystem. In these ways and others, AI seems to be making everything worse.

This is not the whole story. We should not resign ourselves to AI being harmful to humanity. None of us should accept this as inevitable, especially those in a position to influence science, government, and society. Scientists and engineers can push AI towards a beneficial path. Here’s how.

The Academy’s View of AI

A Pew study in April found that 56 percent of AI experts (authors and presenters of AI-related conference papers) predict that AI will have positive effects on society. But that optimism doesn’t extend to the scientific community at large. A 2023 survey of 232 scientists by the Center for Science, Technology and Environmental Policy Studies at Arizona State University found more concern than excitement about the use of generative AI in daily life—by nearly a three to one ratio.

We have encountered this sentiment repeatedly. Our careers of diverse applied work have brought us in contact with many research communities: privacy, cybersecurity, physical sciences, drug discovery, public health, public interest technology, and democratic innovation. In all of these fields, we’ve found strong negative sentiment about the impacts of AI. The feeling is so palpable that we’ve often been asked to represent the voice of the AI optimist, even though we spend most of our time writing about the need to reform the structures of AI development.

We understand why these audiences see AI as a destructive force, but this negativity engenders a different concern: that those with the potential to guide the development of AI and steer its influence on society will view it as a lost cause and sit out that process.

Elements of a Positive Vision for AI

Many have argued that turning the tide of climate action requires clearly articulating a path towards positive outcomes. In the same way, while scientists and technologists should anticipate, warn against, and help mitigate the potential harms of AI, they should also highlight the ways the technology can be harnessed for good, galvanizing public action towards those ends.

There are myriad ways to leverage and reshape AI to improve peoples’ lives, distribute rather than concentrate power, and even strengthen democratic processes. Many examples have arisen from the scientific community and deserve to be celebrated.

Some examples: AI is eliminating communication barriers across languages, including under-resourced contexts like marginalized sign languages and indigenous African languages. It is helping policymakers incorporate the viewpoints of many constituents through AI-assisted deliberations and legislative engagement. Large language models can scale individual dialogs to address climate–change skepticism, spreading accurate information at a critical moment. National labs are building AI foundation models to accelerate scientific research. And throughout the fields of medicine and biology, machine learning is solving scientific problems like the prediction of protein structure in aid of drug discovery, which was recognized with a Nobel Prize in 2024.

While each of these applications is nascent and surely imperfect, they all demonstrate that AI can be wielded to advance the public interest. Scientists should embrace, champion, and expand on such efforts.

A Call to Action for Scientists

In our new book, Rewiring Democracy: How AI Will Transform Our Politics, Government, and Citizenship, we describe four key actions for policymakers committed to steering AI toward the public good.

These apply to scientists as well. Researchers should work to reform the AI industry to be more ethical, equitable, and trustworthy. We must collectively develop ethical norms for research that advance and applies AI, and should use and draw attention to AI developers who adhere to those norms.

Second, we should resist harmful uses of AI by documenting the negative applications of AI and casting a light on inappropriate uses.

Third, we should responsibly use AI to make society and peoples’ lives better, exploiting its capabilities to help the communities they serve.

And finally, we must advocate for the renovation of institutions to prepare them for the impacts of AI; universities, professional societies, and democratic organizations are all vulnerable to disruption.

Scientists have a special privilege and responsibility: We are close to the technology itself and therefore well positioned to influence its trajectory. We must work to create an AI-infused world that we want to live in. Technology, as the historian Melvin Kranzberg observed, “is neither good nor bad; nor is it neutral.” Whether the AI we build is detrimental or beneficial to society depends on the choices we make today. But we cannot create a positive future without a vision of what it looks like.

This essay was written with Nathan E. Sanders, and originally appeared in IEEE Spectrum.

AI Summarization Optimization

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/11/ai-summarization-optimization.html

These days, the most important meeting attendee isn’t a person: It’s the AI notetaker.

This system assigns action items and determines the importance of what is said. If it becomes necessary to revisit the facts of the meeting, its summary is treated as impartial evidence.

But clever meeting attendees can manipulate this system’s record by speaking more to what the underlying AI weights for summarization and importance than to their colleagues. As a result, you can expect some meeting attendees to use language more likely to be captured in summaries, timing their interventions strategically, repeating key points, and employing formulaic phrasing that AI models are more likely to pick up on. Welcome to the world of AI summarization optimization (AISO).

Optimizing for algorithmic manipulation

AI summarization optimization has a well-known precursor: SEO.

Search-engine optimization is as old as the World Wide Web. The idea is straightforward: Search engines scour the internet digesting every possible page, with the goal of serving the best results to every possible query. The objective for a content creator, company, or cause is to optimize for the algorithm search engines have developed to determine their webpage rankings for those queries. That requires writing for two audiences at once: human readers and the search-engine crawlers indexing content. Techniques to do this effectively are passed around like trade secrets, and a $75 billion industry offers SEO services to organizations of all sizes.

More recently, researchers have documented techniques for influencing AI responses, including large-language model optimization (LLMO) and generative engine optimization (GEO). Tricks include content optimization—adding citations and statistics—and adversarial approaches: using specially crafted text sequences. These techniques often target sources that LLMs heavily reference, such as Reddit, which is claimed to be cited in 40% of AI-generated responses. The effectiveness and real-world applicability of these methods remains limited and largely experimental, although there is substantial evidence that countries such as Russia are actively pursuing this.

AI summarization optimization follows the same logic on a smaller scale. Human participants in a meeting may want a certain fact highlighted in the record, or their perspective to be reflected as the authoritative one. Rather than persuading colleagues directly, they adapt their speech for the notetaker that will later define the “official” summary. For example:

  • “The main factor in last quarter’s delay was supply chain disruption.”
  • “The key outcome was overwhelmingly positive client feedback.”
  • “Our takeaway here is in alignment moving forward.”
  • “What matters here is the efficiency gains, not the temporary cost overrun.”

The techniques are subtle. They employ high-signal phrases such as “key takeaway” and “action item,” keep statements short and clear, and repeat them when possible. They also use contrastive framing (“this, not that”), and speak early in the meeting or at transition points.

Once spoken words are transcribed, they enter the model’s input. Cue phrases—and even transcription errors—can steer what makes it into the summary. In many tools, the output format itself is also a signal: Summarizers often offer sections such as “Key Takeaways” or “Action Items,” so language that mirrors those headings is more likely to be included. In effect, well-chosen phrases function as implicit markers that guide the AI toward inclusion.

Research confirms this. Early AI summarization research showed that models trained to reconstruct summary-style sentences systematically overweigh such content. Models over-rely on early-position content in news. And models often overweigh statements at the start or end of a transcript, underweighting the middle. Recent work further confirms vulnerability to phrasing-based manipulation: models cannot reliably distinguish embedded instructions from ordinary content, especially when phrasing mimics salient cues.

How to combat AISO

If AISO becomes common, three forms of defense will emerge. First, meeting participants will exert social pressure on one another. When researchers secretly deployed AI bots in Reddit’s r/changemyview community, users and moderators responded with strong backlash calling it “psychological manipulation.” Anyone using obvious AI-gaming phrases may face similar disapproval.

Second, organizations will start governing meeting behavior using AI: risk assessments and access restrictions before the meetings even start, detection of AISO techniques in meetings, and validation and auditing after the meetings.

Third, AI summarizers will have their own technical countermeasures. For example, the AI security company CloudSEK recommends content sanitization to strip suspicious inputs, prompt filtering to detect meta-instructions and excessive repetition, context window balancing to weight repeated content less heavily, and user warnings showing content provenance.

Broader defenses could draw from security and AI safety research: preprocessing content to detect dangerous patterns, consensus approaches requiring consistency thresholds, self-reflection techniques to detect manipulative content, and human oversight protocols for critical decisions. Meeting-specific systems could implement additional defenses: tagging inputs by provenance, weighting content by speaker role or centrality with sentence-level importance scoring, and discounting high-signal phrases while favoring consensus over fervor.

Reshaping human behavior

AI summarization optimization is a small, subtle shift, but it illustrates how the adoption of AI is reshaping human behavior in unexpected ways. The potential implications are quietly profound.

Meetings—humanity’s most fundamental collaborative ritual—are being silently reengineered by those who understand the algorithm’s preferences. The articulate are gaining an invisible advantage over the wise. Adversarial thinking is becoming routine, embedded in the most ordinary workplace rituals, and, as AI becomes embedded in organizational life, strategic interactions with AI notetakers and summarizers may soon be a necessary executive skill for navigating corporate culture.

AI summarization optimization illustrates how quickly humans adapt communication strategies to new technologies. As AI becomes more embedded in workplace communication, recognizing these emerging patterns may prove increasingly important.

This essay was written with Gadi Evron, and originally appeared in CSO.

Will AI Strengthen or Undermine Democracy?

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/10/will-ai-strengthen-or-undermine-democracy.html

Listen to the Audio on NextBigIdeaClub.com

Below, co-authors Bruce Schneier and Nathan E. Sanders share five key insights from their new book, Rewiring Democracy: How AI Will Transform Our Politics, Government, and Citizenship.

What’s the big idea?

AI can be used both for and against the public interest within democracies. It is already being used in the governing of nations around the world, and there is no escaping its continued use in the future by leaders, policy makers, and legal enforcers. How we wire AI into democracy today will determine if it becomes a tool of oppression or empowerment.

1. AI’s global democratic impact is already profound.

It’s been just a few years since ChatGPT stormed into view and AI’s influence has already permeated every democratic process in governments around the world:

  • In 2022, an artist collective in Denmark founded the world’s first political party committed to an AI-generated policy platform.
  • Also in 2022, South Korean politicians running for the presidency were the first to use AI avatars to communicate with voters en masse.
  • In 2023, a Brazilian municipal legislator passed the first enacted law written by AI.
  • In 2024, a U.S. federal court judge started using AI to interpret the plain meaning of words in U.S. law.
  • Also in 2024, the Biden administration disclosed more than two thousand discrete use cases for AI across the agencies of the U.S. federal government.

The examples illustrate the diverse uses of AI across citizenship, politics, legislation, the judiciary, and executive administration.

Not all of these uses will create lasting change. Some of these will be one-offs. Some are inherently small in scale. Some were publicity stunts. But each use case speaks to a shifting balance of supply and demand that AI will increasingly mediate.

Legislators need assistance drafting bills and have limited staff resources, especially at the local and state level. Historically, they have looked to lobbyists and interest groups for help. Increasingly, it’s just as easy for them to use an AI tool.

2. The first places AI will be used are where there is the least public oversight.

Many of the use cases for AI in governance and politics have vocal objectors. Some make us uncomfortable, especially in the hands of authoritarians or ideological extremists.

In some cases, politics will be a regulating force to prevent dangerous uses of AI. Massachusetts has banned the use of AI face recognition in law enforcement because of real concerns voiced by the public about their tendency to encode systems of racial bias.

Some of the uses we think might be most impactful are unlikely to be adopted fast because of legitimate concern about their potential to make mistakes, introduce bias, or subvert human agency. AIs could be assistive tools for citizens, acting as their voting proxies to help us weigh in on larger numbers of more complex ballot initiatives, but we know that many will object to anything that verges on AIs being given a vote.

But AI will continue to be rapidly adopted in some aspects of democracy, regardless of how the public feels. People within democracies, even those in government jobs, often have great independence. They don’t have to ask anyone if it’s ok to use AI, and they will use it if they see that it benefits them. The Brazilian city councilor who used AI to draft a bill did not ask for anyone’s permission. The U.S. federal judge who used AI to help him interpret law did not have to check with anyone first. And the Trump administration seems to be using AI for everything from drafting tariff policies to writing public health reports—with some obvious drawbacks.

It’s likely that even the thousands of disclosed AI uses in government are only the tip of the iceberg. These are just the applications that governments have seen fit to share; the ones they think are the best vetted, most likely to persist, or maybe the least controversial to disclose.

3. Elites and authoritarians will use AI to concentrate power.

Many Westerners point to China as a cautionary tale of how AI could empower autocracy, but the reality is that AI provides structural advantages to entrenched power in democratic governments, too. The nature of automation is that it gives those at the top of a power structure more control over the actions taken at its lower levels.

It’s famously hard for newly elected leaders to exert their will over the many layers of human bureaucracies. The civil service is large, unwieldy, and messy. But it’s trivial for an executive to change the parameters and instructions of an AI model being used to automate the systems of government.

The dynamic of AI effectuating concentration of power extends beyond government agencies. Over the past five years, Ohio has undertaken a project to do a wholesale revision of its administrative code using AI. The leaders of that project framed it in terms of efficiency and good governance: deleting millions of words of outdated, unnecessary, or redundant language. The same technology could be applied to advance more ideological ends, like purging all statutory language that places burdens on business, neglects to hold businesses accountable, protects some class of people, or fails to protect others.

Whether you like or despise automating the enactment of those policies will depend on whether you stand with or are opposed to those in power, and that’s the point. AI gives any faction with power the potential to exert more control over the levers of government.

4. Organizers will find ways to use AI to distribute power instead.

We don’t have to resign ourselves to a world where AI makes the rich richer and the elite more powerful. This is a technology that can also be wielded by outsiders to help level the playing field.

In politics, AI gives upstart and local candidates access to skills and the ability to do work on a scale that used to only be available to well-funded campaigns. In the 2024 cycle, Congressional candidates running against incumbents like Glenn Cook in Georgia and Shamaine Daniels in Pennsylvania used AI to help themselves be everywhere all at once. They used AI to make personalized robocalls to voters, write frequent blog posts, and even generate podcasts in the candidate’s voice. In Japan, a candidate for Governor of Tokyo used an AI avatar to respond to more than eight thousand online questions from voters.

Outside of public politics, labor organizers are also leveraging AI to build power. The Worker’s Lab is a U.S. nonprofit developing assistive technologies for labor unions, like AI-enabled apps that help service workers report workplace safety violations. The 2023 Writers’ Guild of America strike serves as a blueprint for organizers. They won concessions from Hollywood studios that protect their members against being displaced by AI while also winning them guarantees for being able to use AI as assistive tools to their own benefit.

5. The ultimate democratic impact of AI depends on us.

If you are excited about AI and see the potential for it to make life, and maybe even democracy, better around the world, recognize that there are a lot of people who don’t feel the same way.

If you are disturbed about the ways you see AI being used and worried about the future that leads to, recognize that the trajectory we’re on now is not the only one available.

The technology of AI itself does not pose an inherent threat to citizens, workers, and the public interest. Like other democratic technologies—voting processes, legislative districts, judicial review—its impacts will depend on how it’s developed, who controls it, and how it’s used.

Constituents of democracies should do four things:

  • Reform the technology ecosystem to be more trustworthy, so that AI is developed with more transparency, more guardrails around exploitative use of data, and public oversight.
  • Resist inappropriate uses of AI in government and politics, like facial recognition technologies that automate surveillance and encode inequity.
  • Responsibly use AI in government where it can help improve outcomes, like making government more accessible to people through translation and speeding up administrative decision processes.
  • Renovate the systems of government vulnerable to the disruptive potential of AI’s superhuman capabilities, like political advertising rules that never anticipated deepfakes.

These four Rs are how we can rewire our democracy in a way that applies AI to truly benefit the public interest.

This essay was written with Nathan E. Sanders, and originally appeared in The Next Big Idea Club.

EDITED TO ADD (11/6): This essay was republished by Fast Company.

What should be included in a data science curriculum for schools?

Post Syndicated from Jan Ander original https://www.raspberrypi.org/blog/what-should-be-included-in-a-data-science-curriculum-for-schools/

Current artificial intelligence (AI) methods, especially machine learning (ML), rely heavily on data. To complement our work on AI literacy, we have been investigating what data science teaching resources and education research are currently available. Our goal is to work out what data science concepts should be taught in a data science curriculum for schools.

In a computing classroom, a smiling girl raises her hand.

Read on to find out what resources and materials we have reviewed, and what concept themes we have identified.

What is data science? Why is teaching it important?

Data science is an interdisciplinary science of learning from large datasets, aided by modern computational tools and methods (Ow‑Yeong et al., 2023). We see data science skills as fundamental for using, creating, and thinking critically about:

  • Insights from data, generally
  • Data-driven computational tools and methods (such as machine learning) and their outputs and predictions, specifically
Someone explains a graph shown on a computer screen.

To navigate a world where decision making in many areas is influenced by data-driven insights and predictions, young people need to be taught about data science. Data science skills empower young people to become critical thinkers, discerning consumers, adaptable professionals, and informed citizens.

Worldwide, countries are taking a variety of approaches to introducing data science into their education systems, as highlighted in a 2024 report from the coalition Data Science 4 Everyone.

An overview of data science education across the world
An overview of data science education across the world. Source: Beyond Borders 2024: Primary and Secondary Data Science Education Around the World, republished with kind permission of Data Science 4 Everyone. Click the image to enlarge it.

In some countries, such as India and Israel, data science education is an established school subject. It is taught as part of the curriculum in at least one of the primary, secondary, or post-16 age phases. Meanwhile in other countries, for example Canada, Germany, and Poland, data science is a very new school subject, or there are still only recommendations to develop it into a school subject.

While we are currently considering what a comprehensive data science curriculum should include, we already offer several resources to support you with your teaching about data science and data-driven technologies. You can find a list of these resources at the end of this blog. Now, however, I’ll give you an overview of our recent work to identify concepts for a data science curriculum that fits with our approach to AI literacy.

Data science education: What should we teach?

To answer the question ‘What should we teach about data science to learners aged 5 to 19?’, we undertook a grey literature review of data science teaching materials. A grey literature review is structured like an academic literature review and conducted with the same rigour. The difference is that a grey literature review also considers publications that have not been peer-reviewed, including reports, white papers, curriculum materials, and similar resources.

To orient our work, we combined four frameworks for data science and AI/ML education:

With these combined frameworks as our map, we reviewed 79 data science learning resources. The resources varied:

  • In quality in terms of clarity and teaching approach
  • In their focus, e.g. on maths, coding, or a specific field such as biology
  • In their perspective on data science, with some prioritising theory and others real-world applications

From among the 79 resources, we chose 9 that included clear learning outcomes, and that together covered a wide field of concepts. We examined these 9 in detail to extract 181 explicit and implicit data science concepts. Next, we grouped the concepts into themes, and finally we refined these themes by comparing them against the four frameworks listed above.

The themes we have identified for a data science curriculum are:

  • Fundamentals of data literacy: Key terms and definitions
  • Understanding bias in data
  • Ethical responsibility in data use
  • Data creation, curation, and transformation
  • Analysis and modelling: Maths and statistics fundamentals
  • ML principles
  • Deploying and maintaining ML applications
  • Software tools and programming
  • Data visualisation
  • Presenting findings effectively

This set of themes both fits with the frameworks by Olari and Romeike and Data Science 4 Everyone, and expands them by covering ML principles and programming approaches and calling out data bias and ethics.

What’s next for this work?

Through our grey literature review on data science education, we’ve:

  • Pinpointed a large set of candidate concepts that could be taught within a data science curriculum
  • Created a set of clear themes to structure our work going forward

Our next step is to shape these candidate concepts into a progression framework to describe their relationships and establish which concepts could be taught at each age or phase of schooling.

Young people studying in a computing classroom.

The literature review also gave us an overview of the pedagogical approaches and tools used for teaching data science concepts. These findings will become useful once we start designing learning activities.

You’ll hear more about how this work is going here on our blog and on our social channels. In the meantime, comment below to let us know what you think about the themes, or to tell us what you’d like to see in a data science curriculum for the learners you work with.


Our resources related to data science

Classroom resources

You can read about our thinking behind the data science-related teaching resources we’ve created so far in our ‘Data and information within the computing curriculum’ report from 2019.

  • The report lists the data-related units within The Computing Curriculum materials, which we no longer update but continue to offer as free downloads. Updated classroom materials are available as part of the Computing materials we created for Oak National Academy in the UK for ages 5–11 and ages 12–19.
  • The Ada Computer Science platform offers learning materials on data and information, and on AI and ML, for ages 14–19.

You might also be interested in exploring the Experience AI programme, which offers everything teachers need to help students develop a foundational understanding of data-driven AI technologies, their social and ethical implications, and the role that AI can play in their lives.

Teacher training and development resources

Our free online course ‘Teach teens computing: Machine learning and AI‘ helps teachers understand and explain the types of problems that ML can help to solve, discuss how AI is changing the world, and think about the ethics of collecting data to train a ML model.

Teaching young people to understand data-driven AI technologies means teaching them thinking skills that are different to those needed to understand rule-based computer systems. You can read about these Computational Thinking 2.0 skills in our Quick Read PDF.

Our current research seminar series focuses on teaching about AI and data science. Sign up for an upcoming seminar session (the next one is on 11 November) or catch up on past sessions to find out what the latest research findings are in this area. You can also revisit our 2021/22 series on the same topic to see how work in this area has developed. The Raspberry Pi Computing Education Research Centre also has ongoing projects in the area of AI education for you to explore.

The post What should be included in a data science curriculum for schools? appeared first on Raspberry Pi Foundation.

The AI-Designed Bioweapon Arms Race

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/10/the-ai-designed-bioweapon-arms-race.html

Interesting article about the arms race between AI systems that invent/design new biological pathogens, and AI systems that detect them before they’re created:

The team started with a basic test: use AI tools to design variants of the toxin ricin, then test them against the software that is used to screen DNA orders. The results of the test suggested there was a risk of dangerous protein variants slipping past existing screening software, so the situation was treated like the equivalent of a zero-day vulnerability.

[…]

Details of that original test are being made available today as part of a much larger analysis that extends the approach to a large range of toxic proteins. Starting with 72 toxins, the researchers used three open source AI packages to generate a total of about 75,000 potential protein variants.

And this is where things get a little complicated. Many of the AI-designed protein variants are going to end up being non-functional, either subtly or catastrophically failing to fold up into the correct configuration to create an active toxin.

[…]

In any case, DNA sequences encoding all 75,000 designs were fed into the software that screens DNA orders for potential threats. One thing that was very clear is that there were huge variations in the ability of the four screening programs to flag these variant designs as threatening. Two of them seemed to do a pretty good job, one was mixed, and another let most of them through. Three of the software packages were updated in response to this performance, which significantly improved their ability to pick out variants.

There was also a clear trend in all four screening packages: The closer the variant was to the original structurally, the more likely the package (both before and after the patches) was to be able to flag it as a threat. In all cases, there was also a cluster of variant designs that were unlikely to fold into a similar structure, and these generally weren’t flagged as threats.

The research is all preliminary, and there are a lot of ways in which the experiment diverges from reality. But I am not optimistic about this particular arms race. I think that the ability of AI systems to create something deadly will advance faster than the ability of AI systems to detect its components.

ASRock Rack 8U8X-GNR2 SYN B200 Review NVIDIA HGX B200 8-GPU Server

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/asrock-rack-8u8x-gnr2-syn-b200-review-nvidia-hgx-b200-8-gpu-server-intel-xeon/

In our ASRock Rack 8U8X-GNR2 SYN B200 review, we see how this NVIDIA HGX B200 8-GPU server exemplifies ASRock Rack’s engineering flair

The post ASRock Rack 8U8X-GNR2 SYN B200 Review NVIDIA HGX B200 8-GPU Server appeared first on ServeTheHome.