Tag Archives: Graviton

Amazon MSK Express brokers available on AWS Graviton4-based M8g instances

Post Syndicated from Charishma Makineni original https://aws.amazon.com/blogs/big-data/amazon-msk-express-brokers-available-on-aws-graviton4-based-m8g-instances/

Teams running Apache Kafka for real-time streaming often face a tradeoff: better performance or lower costs. Now, you can have both. Get faster throughput and lower tail latency from the same cluster, with no increase in infrastructure costs. Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers are now available on AWS Graviton4-based M8g instances. Compared with Express brokers on M7g, Express brokers on M8g have 15 percent lower broker-hour pricing. You also no longer pay the broker-side cost when moving data across Availability Zones for client traffic, which reduces total cross-AZ data transfer costs by 50 percent. With M8g, Express brokers now support a 24xlarge instance size, giving you more headroom to scale. In our testing at the same broker size and load, P99 produce latency was 21–54 percent lower on M8g, and broker CPU was 9–11 percentage points lower. Consumers that fell behind cleared up to 3x more backlog in 30 minutes. P99 produce latency is the time to acknowledge a produced record for the slowest 1 percent of requests, a common measure of tail latency.

In this post, we cover what changes with Express brokers on M8g and how it affects cost. We share benchmark results comparing M8g to M7g, and we show you how to move your cluster to M8g.

Express brokers on M8g

Express brokers give you up to 3x more throughput per broker, up to 20x faster scaling, and up to 90% faster recovery than Standard brokers. Express brokers manage storage and broker tuning for you, so your team spends time on streaming applications instead of cluster maintenance.

Express brokers on M8g keep what Express brokers support on M7g: the same Kafka versions, authentication methods, custom configurations, Amazon CloudWatch metrics, and Open Monitoring with Prometheus. For sizes available on both generations, storage and network throughput per broker are the same as Express brokers on M7g, so you can move to M8g at the size you run today and keep the same per-broker throughput.

The following table compares Express brokers on M7g and M8g.

Express on M7g Express on M8g
Broker-hour price Baseline 15% lower
Amazon MSK broker-side cross-AZ charge for client traffic Charged Not charged
Amazon MSK EC2-side cross-AZ charge for client traffic Baseline Same
Largest broker size 16xlarge 24xlarge
Throughput per broker at each size Baseline Same
Connection limit per broker Baseline Same
Data-in and storage pricing Baseline Same

AWS offers Express brokers on M8g in the following sizes. Use the recommended throughput and partition limits when you size a cluster.

Broker size vCPUs Memory (GiB) Recommended ingress per broker (MBps) Recommended egress per broker (MBps) Recommended partitions per broker Max partitions per broker
express.m8g.large 2 8 15.6 31.2 1,000 1,500
express.m8g.xlarge 4 16 31.2 62.5 1,000 2,000
express.m8g.2xlarge 8 32 62.5 125 2,500 4,000
express.m8g.4xlarge 16 64 124.9 249.8 6,000 8,000
express.m8g.8xlarge 32 128 250 500 12,000 16,000
express.m8g.12xlarge 48 192 375 750 16,000 24,000
express.m8g.16xlarge 64 256 500 1,000 20,000 32,000
express.m8g.24xlarge 96 384 667 1,334 20,000 32,000

What this means for your workloads

  • Latency-sensitive and bursty workloads – Lower P99 produce latency means fewer slow acknowledgments during traffic spikes, which is where tail latency affects your end users.
  • Workloads that have outgrown 16xlarge – With the 24xlarge size, you can run more throughput on each broker. An express.m8g.24xlarge broker supports 667 MBps of recommended ingress, compared with 500 MBps on express.m8g.16xlarge. If you have a throughput-bound workload and run many 16xlarge brokers today, you can run fewer 24xlarge brokers.
  • Multi-AZ pipelines – Lower broker-hour pricing and no broker-side cross-AZ charge lower the cost of running a cluster across three Availability Zones, with no change to your application code.
  • Workloads that replay data or recover from lag – Consumers that fall behind after an outage, a deployment, or a reprocessing job catch up faster on M8g. In our test, consumers on M8g cleared up to 3x more backlog in 30 minutes than on M7g, so you recover sooner without adding brokers.

Benchmark: Express on M8g compared with Express on M7g

We wanted to see how M8g behaves under the same load as M7g, so we changed only the broker generation and kept everything else the same.

Test setup

  • Two Express clusters, one on express.m8g.large and one on express.m7g.large, each with three brokers across three Availability Zones in US East (N. Virginia).
  • Kafka version 3.9.x (KRaft mode) on both clusters.
  • Transport Layer Security (TLS) encryption in transit and AWS Identity and Access Management (IAM) access control.
  • Six topics with 64 partitions each, replication factor 3, and min.insync.replicas=2.
  • Producer settings: acks=all, linger.ms=5, batch.size=65536 (64 KiB), compression.type=none.
  • One consumer group per topic.
  • Fixed message size of 512 bytes.
  • Three c7i.2xlarge client instances, one in each Availability Zone, running kafka-producer-perf-test and kafka-consumer-perf-test from Apache Kafka 3.9.1 with the Amazon MSK IAM authentication library. Each client drove both clusters at the same time, so both clusters saw the same client and network conditions. Client CPU stayed below 20% and network throughput below 10% of instance capacity at every step, so clients were never the bottleneck.

Express brokers manage server-side settings such as network and I/O threads, so there was nothing to tune on the broker side.

We stepped ingress from 2–16 MBps per broker in 2 MBps increments. We held each step for about 10 minutes and recorded values only after the cluster reached steady state.

P99 produce latency

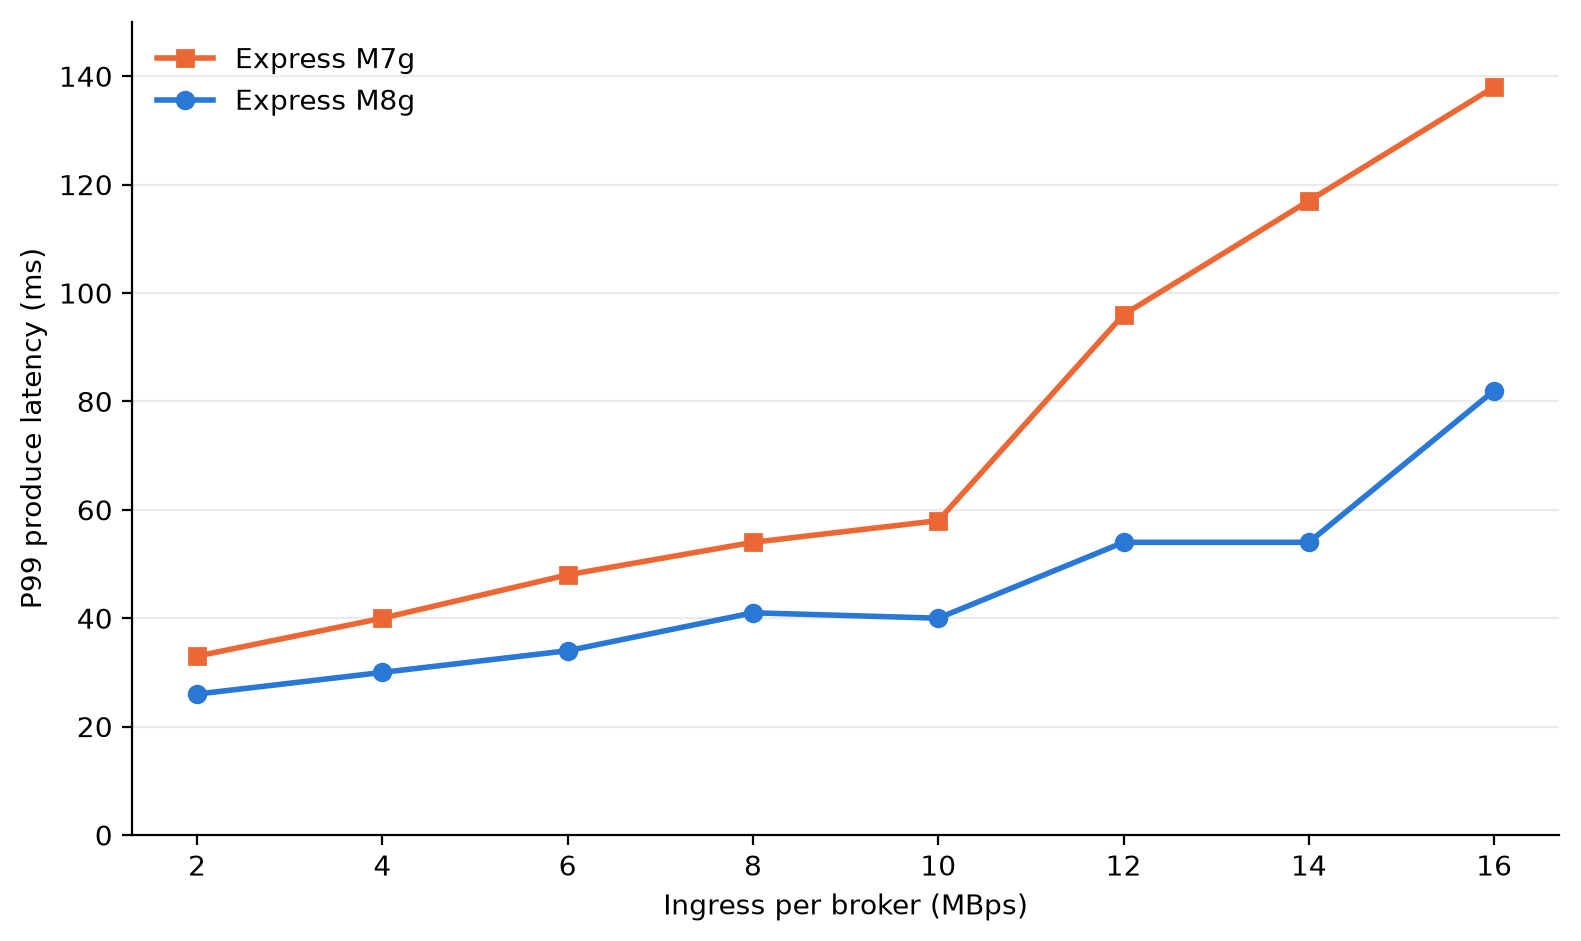
P99 produce latency was lower on M8g at every step. At 6 MBps per broker, P99 was 34 ms on M8g and 48 ms on M7g, 29 percent lower. At 12 MBps per broker, P99 was 54 ms on M8g and 96 ms on M7g, 44 percent lower. The difference was largest at 14 MBps per broker, where P99 was 54 ms on M8g and 117 ms on M7g, 54 percent lower.

Ingress per broker (MBps) M8g P99 (ms) M7g P99 (ms) Reduction
2 26 33 21%
4 30 40 25%
6 34 48 29%
8 41 54 24%
10 40 58 31%
12 54 96 44%
14 54 117 54%
16 82 138 41%
Line chart of P99 produce latency by ingress per broker, lower for express.m8g.large than express.m7g.large at every step

Figure 1: Client P99 produce latency by ingress per broker for express.m8g.large and express.m7g.large

Broker CPU

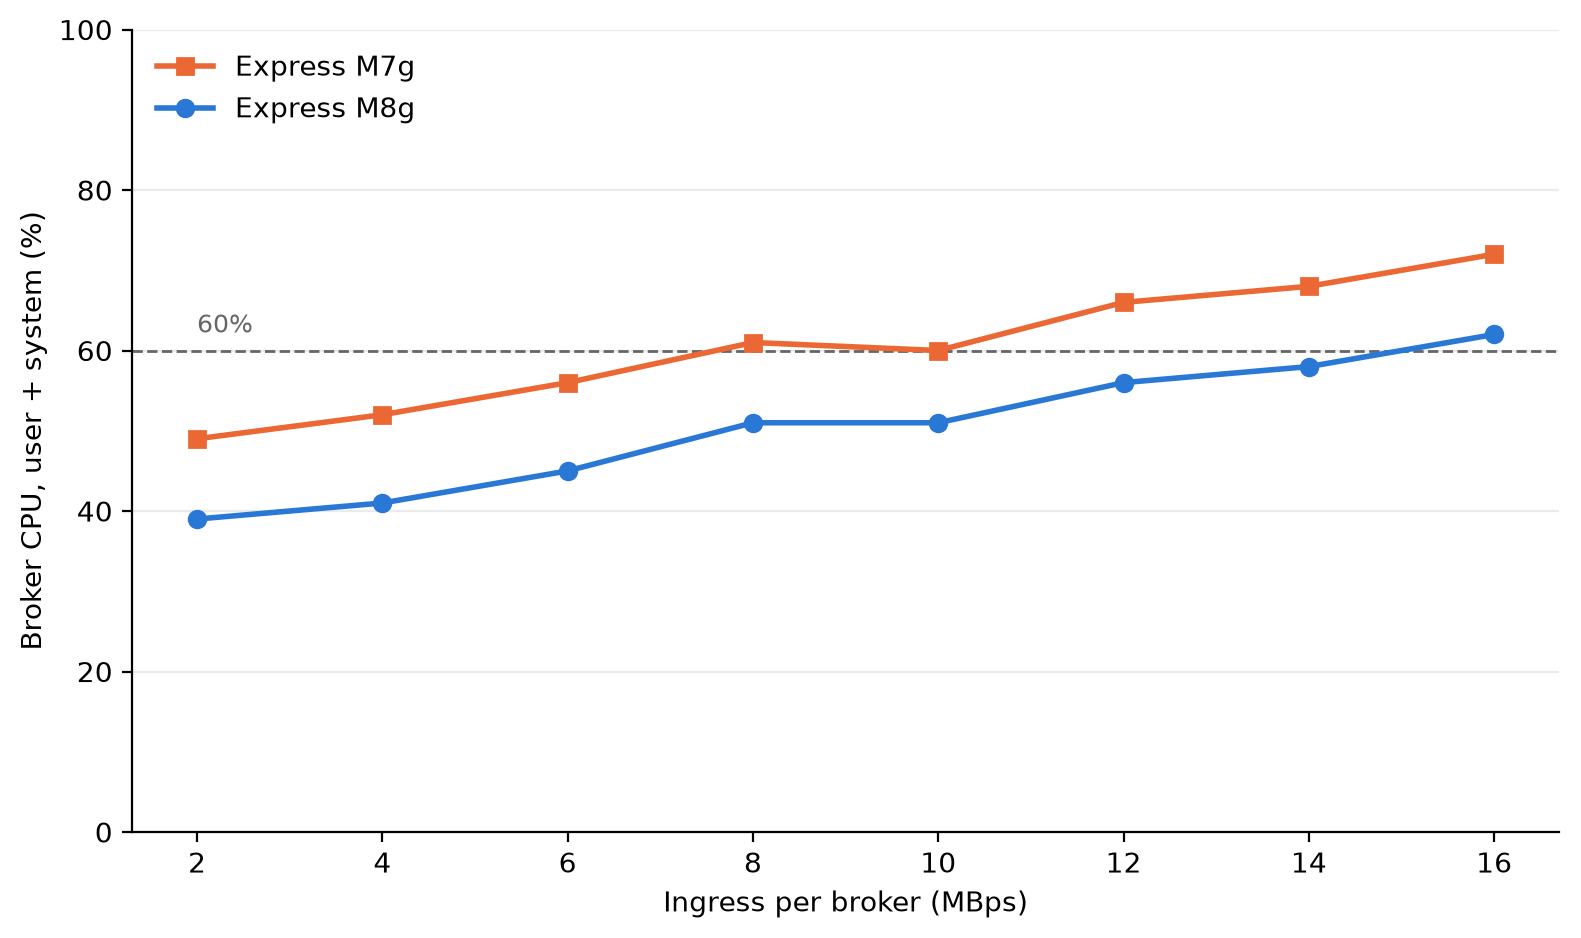
At the same load, M8g brokers used less CPU. Broker CPU (user plus system, averaged across the three brokers) was 9–11 percentage points lower on M8g at each step. At 6 MBps per broker, M8g ran at 45 percent and M7g at 56 percent. M7g brokers ran at 60 percent or higher from 8 MBps per broker. M8g brokers stayed below 60 percent through 14 MBps per broker. That gives you more room on each broker for traffic spikes and broker maintenance.

Ingress per broker (MBps) M8g CPU (%) M7g CPU (%)
2 39 49
4 41 52
6 45 56
8 51 61
10 51 60
12 56 66
14 58 68
16 62 72
Line chart of average broker CPU by ingress per broker, 9 to 11 points lower on express.m8g.large than express.m7g.large

Figure 2: Average broker CPU (user plus system) at each load step for express.m8g.large and express.m7g.large

Consumer catch-up

When consumers fall behind, for example after an outage or a deployment, they must read the backlog while producers keep writing. We ran a separate test to measure how fast consumers catch up on each generation. This test used a new pair of express.m8g.large and express.m7g.large clusters, with the same Kafka version, authentication, and encryption as the latency test, and the following differences:

  • Three topics with 440 partitions each and replication factor 3, for 1,320 partition replicas per broker.
  • 1 KiB records, acks=all, batch.size=65536 (64 KiB), linger.ms=10, and compression.type=none.
  • Producers wrote about 5.7 MBps per broker (35 percent of the recommended ingress for large brokers) for 3 hours, with 2 hours of retention.
  • One consumer group read new records as they arrived. Every 30 minutes, two more groups of 30 consumers each restarted with a new group ID and read from the earliest offset. Each cycle then read the whole retained backlog.
  • Four c5.4xlarge client instances for each cluster (two for producers and two for consumers). Client CPU stayed below 35 percent, so the clients were never the bottleneck.

With a backlog of about 30 million records (about 30 GB), consumers on M8g caught up in 13–18 minutes. On M7g, consumers had not caught up after 30 minutes and still had 2–9 million records to read. At the largest backlog, about 120 million records, consumers on M8g cleared about 91 million records in 30 minutes, compared with 30–32 million on M7g. That is about 3x more backlog cleared in 30 minutes.
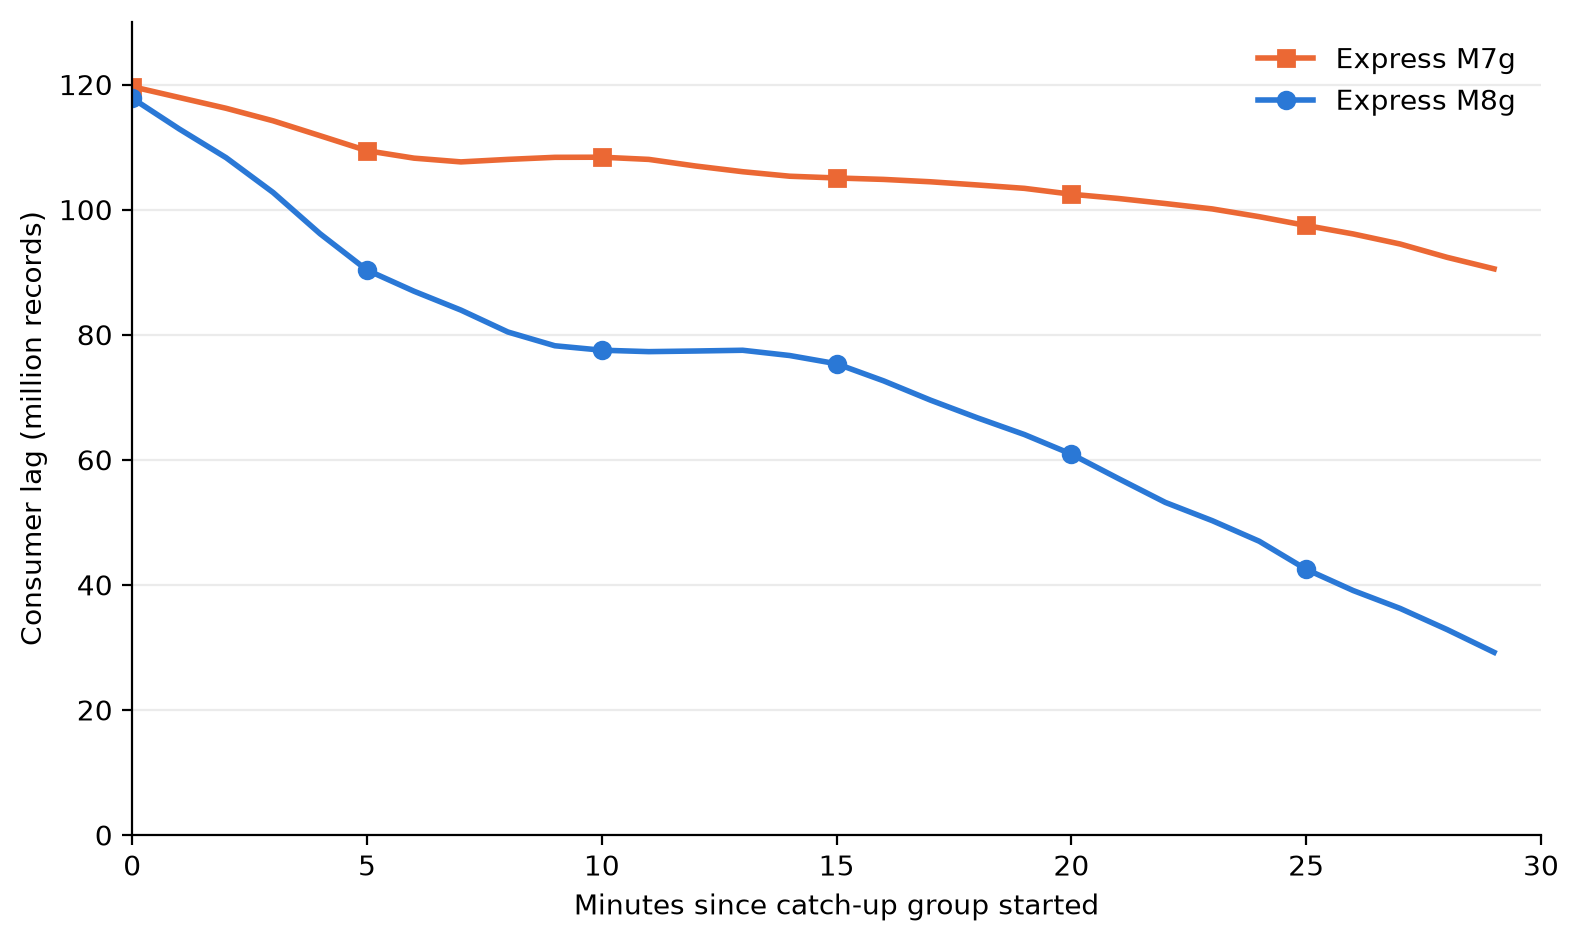
Line chart of consumer lag over 30 minutes for express.m8g.large and express.m7g.large, starting from about 120 million records. After 30 minutes, M8g lag is down to about 29 million records. M7g lag is still about 91 million records.

Figure 3: Consumer lag after a catch-up group starts from the earliest offset of a 120-million-record backlog, for express.m8g.large and express.m7g.large

Your results depend on load, message size, batch settings, consumer group count, and broker size. We ran this test on the large size only. To estimate your results, create an Express cluster on M8g and run your own workload against it. When you finish testing, delete the cluster to avoid ongoing charges.

Cost

Express brokers on M8g lower your costs in two ways: lower broker-hour pricing, and no broker-side charge for cross-AZ client traffic.

Broker-hour pricing

Broker-hour pricing for Express brokers on M8g is 15 percent lower than Express brokers on M7g at each size. In US East (N. Virginia), express.m8g.large costs $0.347 per hour and express.m7g.large costs $0.408 per hour. Data-in and storage pricing don’t change.

Cross-AZ data transfer

Many production Kafka clusters run across three Availability Zones. When a client connects to a broker in a different Availability Zone, the traffic between them is cross-AZ traffic. With clients spread evenly across three Availability Zones, about two-thirds of client traffic is cross-AZ. Each request goes to the partition leader, which can be in any Availability Zone.

Standard AWS data transfer charges for cross-AZ traffic in US East (N. Virginia) are $0.01 per GB on the sending side and $0.01 per GB on the receiving side, or $0.02 per GB in total. With Express brokers on M8g, AWS doesn’t charge the broker side, so cross-AZ traffic between your clients and brokers costs $0.01 per GB in total. That’s 50 percent lower than on M7g.

The following table shows the cross-AZ data transfer charge per GB of client traffic for each generation.

Express on M7g Express on M8g
Client side $0.01 per GB $0.01 per GB
Broker side $0.01 per GB Not charged
Total per GB of cross-AZ client traffic $0.02 $0.01

You can reduce consumer cross-AZ traffic with rack awareness. Producers must write to the partition leader, which can be in any Availability Zone. Consumers can read from a replica in their own Availability Zone instead. To turn this on, set replica.selector.class to org.apache.kafka.common.replica.RackAwareReplicaSelector in your cluster configuration. Set client.rack on each consumer to the Availability Zone ID it runs in (for example, use1-az1). Consumers that read from a local replica don’t incur cross-AZ traffic, so you pay cross-AZ charges only on the produce side. On Express brokers on M8g, that produce-side cross-AZ traffic costs $0.01 per GB. If you don’t use rack awareness, your consumer cross-AZ traffic also costs 50 percent less on M8g, because AWS doesn’t charge the broker side.

For example, consider a cluster of three large brokers in US East (N. Virginia) with 30 MBps of ingress and two consumer groups (60 MBps of egress). Over a 30-day month, about 155,520 GB of client traffic crosses Availability Zones.

Monthly cost Express on M7g Express on M8g Express on M8g with rack awareness
Broker hours (3 brokers × 720 hours) $881.28 $749.52 $749.52
Cross-AZ produce traffic (51,840 GB) $1,036.80 $518.40 $518.40
Cross-AZ consume traffic (103,680 GB) $2,073.60 $1,036.80 $0
Total $3,991.68 $2,304.72 $1,267.92

With rack awareness, the cross-AZ charge in this example drops from $1,555.20 to $518.40 per month. Reading from a follower replica can add a small amount of end-to-end latency, so test with your workload. For setup steps, see Reduce network traffic costs of your Amazon MSK consumers with rack awareness.

Data-in and storage charges are the same on both generations, so they aren’t included.

To estimate your own cross-AZ traffic, add the BytesInPerSec and BytesOutPerSec CloudWatch metrics across your brokers. Each 1 MBps sustained over a 30-day month is about 2,592 GB. Multiply the total by two-thirds if your clients are spread evenly across three Availability Zones. If your consumers use rack awareness, count only BytesInPerSec.

This applies only to traffic between your clients and brokers. Replication traffic between brokers, and between metadata nodes and brokers, isn’t charged on either generation. For details, see Amazon MSK pricing.

Move to Express brokers on M8g

You have three options, depending on where your workload runs today.

Create a cluster on M8g

In the Amazon MSK console, choose Create cluster, choose Express as the broker type, and choose an M8g size. You can also use the CreateClusterV2 API.

Update an Express cluster on M7g

You can change the broker type of a cluster from M7g to M8g in place. Amazon MSK updates brokers one at a time, so clients keep producing and consuming during the update.

aws kafka update-broker-type \
    --cluster-arn <your-cluster-arn> \
    --current-version <current-cluster-version> \
    --target-instance-type express.m8g.large

Before you update, check that your partition count per broker and your throughput fit within the limits for the target size.

Move from Standard brokers or a self-managed Kafka cluster

Create a new Express cluster on M8g, and then use Amazon MSK Replicator to copy your topics, data, and consumer group offsets to it. For steps, see Migrate from Standard brokers to Express brokers or Migrate from non-MSK Apache Kafka clusters.

Considerations

  • Connection limits per broker don’t change.
  • The pricing and performance changes in this post apply to Express brokers. M8g is also available for Standard brokers. For Standard broker pricing, see the Amazon MSK pricing page.

Conclusion

Express brokers on Graviton4-based M8g instances lower the cost of running Kafka on Amazon MSK and lower tail latency for the same load. You get 15 percent lower broker-hour pricing, no Amazon MSK broker-side charge for cross-AZ client traffic, and a 24xlarge size for workloads that need more capacity per broker. In our benchmark at the large size, P99 produce latency was 21–54 percent lower, broker CPU was 9–11 percentage points lower, and consumers that fell behind cleared up to 3x more backlog in 30 minutes than on M7g.

To get started, create an Express cluster on M8g or update your Express cluster on M7g. Amazon MSK supports M8g sizes in every AWS Region that supports Express brokers. For pricing, see Amazon MSK pricing. For setup steps, see the Amazon MSK Developer Guide.

If you have questions or feedback, leave a comment on this post or start a thread on AWS re:Post.


About the authors

Charishma Makineni

Charishma Makineni

Charishma is a Senior Specialist Solutions Architect for streaming at AWS. She helps customers build real-time streaming architectures using services like Amazon Kinesis Data Streams and Amazon Managed Streaming for Apache Kafka (Amazon MSK). Outside of work, Charishma enjoys being outdoors, gardening, and reading.

Swapna Bandla

Swapna Bandla

Swapna is a Senior Streaming Solutions Architect on the AWS Streaming Specialist SA Team. She has a passion for understanding customers’ data and analytics needs, and empowering them to develop cloud-based, well-architected solutions. Outside of work, she enjoys spending time with her family.

Huyam Hasan

Huyam Hasan

Huyam is a Solutions Architect II at AWS, based in Austin, TX. She works with enterprise customers in travel, hospitality, and gaming to design real-time data and streaming architectures, and helps them bring generative and agentic AI into production. She is passionate about turning data into business outcomes for her customers.

AWS Graviton support for Java in AWS Transform continuous modernization

Post Syndicated from Harvinder Nagpal original https://aws.amazon.com/blogs/devops/aws-graviton-support-for-java-in-aws-transform-continuous-modernization/

AWS Transform continuous modernization now supports Graviton readiness assessment and remediation for Java, generally available since October 29, 2026. Use it to move Java applications to AWS Graviton-based instances. A readiness assessment finds the Arm64 compatibility issues in a repository, and a remediation skill resolves them in code, which you then validate on Arm64 and deploy.

AWS Graviton-based instances deliver better price-performance than comparable x86 instances. Teams planning a migration therefore face two questions about their estate: which applications are ready to move, and what has to change in the ones that are not.

Answering that repository by repository does not scale. The Java code itself is rarely the obstacle. What decides readiness is an application’s dependencies, and whether each one supports Arm64. Establishing that manually across an estate is slow, repetitive, and prone to error.

In this post, you learn how to analyze a Java repository for AWS Graviton readiness, remediate the findings, validate the change on Arm64, and deploy and run the result on a Graviton-based instance.

Solution overview

AWS Transform continuous modernization connects to your source provider, discovers your repositories, analyzes them for technical debt, remediates what it finds, and opens a pull request with the result. Analysis can also run on a schedule, so once your applications are running on Graviton you can keep checking them as dependencies change.

Two skills cover the Graviton migration:

Skill What it does
AWS/graviton-readiness-assessment Scans a repository for native libraries, architecture-specific code, and Arm64-incompatible transitive dependencies. Read-only. It does not modify source or project files.
AWS/java-x86-to-graviton Resolves the findings the analysis returned: updates native libraries, upgrades blocking dependencies, adds aarch64 handling, updates Dockerfiles for multi-architecture builds, and applies Graviton JVM flags.

The readiness assessment does not change your code. It produces findings, one for each Arm64 compatibility issue it identifies. Each finding carries a severity, a category, file references, and the transformation that resolves it, so you can triage a portfolio and drive remediation directly from the findings.

Continuous modernization runs in two places. Remotely, it uses infrastructure in your AWS account or infrastructure that AWS Transform manages. Locally, it runs on your own machine. For a Graviton migration, that choice decides what can be validated:

AWS Transform-managed Customer-managed (Amazon Elastic Compute Cloud (Amazon EC2) or AWS Batch) Local
Analysis Supported, nothing to provision Supported Supported
Remediation Not supported Supported (x86 only) Supported

Note: Continuous modernization currently provisions remote infrastructure in your account on the x86 architecture. A remote remediation produces the Arm64 code changes, but it cannot build or test them on Arm64 — you do that in your own Arm64 pipeline before you merge. On an Arm64 host, a local run builds on the target architecture as part of the remediation and leaves the change on disk, which is why this post runs it locally.

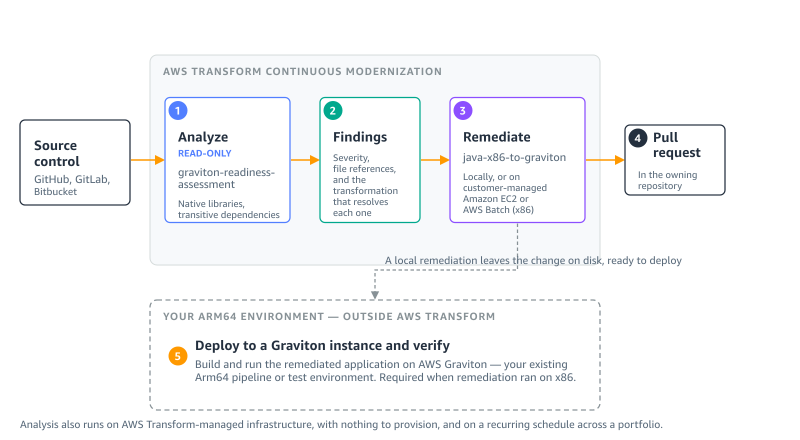
Step 5 in the following diagram, deploying to a Graviton-based instance, is beyond the scope of AWS Transform, whose output is the validated change and the pull request. In your environment, Step 5 is your existing Arm64 pipeline or test environment.

Steps 1 to 4 run inside AWS Transform continuous modernization; step 5, deploying to a Graviton instance, runs in your own Arm64 environment

Figure 1: Where each step runs. Steps 1–4 are AWS Transform continuous modernization. Step 5 is your own Arm64 environment

The walkthrough covers these steps:

  1. Connect your source and discover repositories.
  2. Analyze the repository for Graviton readiness.
  3. Remediate the findings.
  4. Validate the build on Arm64.
  5. Deploy to a Graviton instance and verify.
  6. Scale across your portfolio.

For the full command surface, refer to Working with continuous modernization in the AWS Transform User Guide.

Prerequisites

To follow this walkthrough, you need:

  • An AWS account with AWS Transform enabled for your user identity, which gives you access to the AWS Transform web application. For instructions, refer to Setting up AWS Transform.
  • An AWS Region where AWS Transform is available. For the current list, refer to Supported Regions for AWS Transform.
  • AWS credentials with permission to use AWS Transform.
  • The AWS Transform CLI, installed with the setup script, and Node.js 20 or later. Install Node.js from the Node.js website, because some package managers ship an older version.
  • Git, used for version control during the transformation.
  • A source connection: a GitHub, GitLab, or Bitbucket personal access token with repository scope, or a local folder containing checkouts you already have. The readiness assessment is read-only, so it needs no write access to your code. Remediation needs write access only if you want it to open the pull request.
  • For remediation, an Arm64 host, such as a Graviton-based Amazon EC2 instance. A local remediation builds its changes on the machine it runs on, so running it on Arm64 validates them on the target architecture. On x86, the remediation skill produces the code changes but cannot build or test them on Arm64.
  • Java 8 or later. These capabilities do not change Java versions. If you also need a version upgrade, run the AWS/java-version-upgrade transformation first. For more information, refer to the AWS Transform User Guide.

This post uses Amazon Corretto 21, Gradle 8.13, and a c7g.2xlarge instance running Amazon Linux 2023.

The sample application

This walkthrough uses TASSEL, an open source genetics toolkit. It is a Gradle project on Java 21 of about 245,000 lines of code, and it is a useful example because its dependency on x86 is typical rather than exotic.

TASSEL’s inner loop is matrix algebra, and it delegates that work to a native BLAS library through a Java Native Interface (JNI) bridge. It also reads and writes scientific data formats through libraries that ship compiled binaries inside their JAR files. Those binaries are built per architecture, and several of them have no Arm64 build — which is exactly what the readiness assessment is looking for.

If you do not have a sample application of your own, clone this one into the folder you will register as a source:

git clone https://github.com/btmonier/tassel-renovate.git

Connect your source and discover repositories

In this step, you register where your code lives and list the repositories that AWS Transform can see.

To connect a source and discover repositories

  1. Open a terminal and set the Region for the session with export AWS_REGION=us-east-1.
  2. Enter atx ct status to confirm the CLI reaches the service. It prints a summary of the sources, repositories, analyses, and findings in your account.
  3. Register a hosted source with atx ct source add --name graviton-demo --provider github --org my-org --token "$PAT", or a local folder with atx ct source add --name graviton-demo --provider local --path ~/code.
  4. Enter atx ct discovery scan --source graviton-demo to discover the repositories.
  5. Enter atx ct repository list --source graviton-demo --language java to confirm what was found.

Analyze the repository for Graviton readiness

In this step, you run the readiness assessment and review what it found.

To run the analysis

  1. Enter the following command:
    atx ct analysis run --type graviton-readiness \
    --source graviton-demo --repo tassel-renovate

  2. Enter atx ct analysis get --id <analysis-id> to follow progress.
  3. Enter atx ct findings count --by severity --repo graviton-demo::tassel-renovate to see the severity breakdown. For this repository it returned seven findings: three high, three medium, and one low.

You can also run the analysis from the AWS Transform web application.

To run the analysis on the console

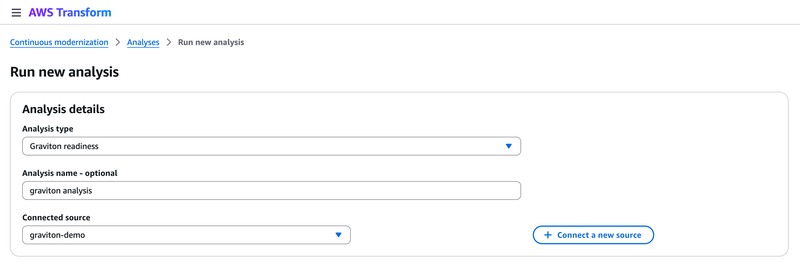
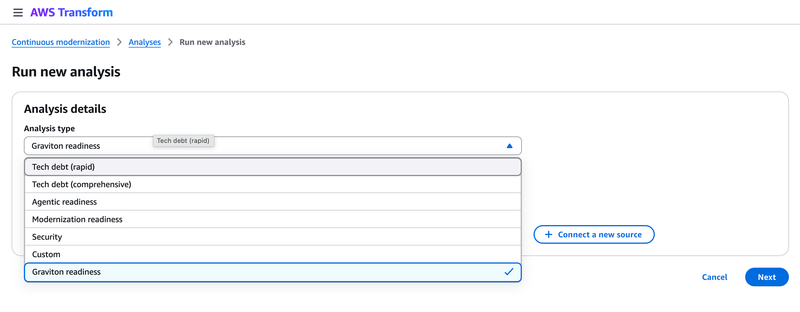
  1. On the Analyses tab, choose Run new analysis.
  2. For Analysis type, choose Graviton readiness.
  3. For Analysis name, enter a name for the run.
  4. For Connected source, select your source.
  5. Choose Next to select repositories and an infrastructure mode, then choose Run. To run it on a recurring cadence, choose Schedule.
The Analysis type list in the AWS Transform web application, with Graviton readiness selected

Figure 2: Graviton readiness in the Analysis type list

The Run new analysis page configured for a Graviton readiness analysis

Figure 3: Configuring a Graviton readiness analysis against a connected source

What the analysis found

The analysis returned seven findings for this repository. The following examples are two of the seven, chosen because the difference between them is why this analysis is worth running. It also reported build configuration and JVM flag issues not shown here.

The application’s own code – TASSEL loads a native BLAS bridge with System.loadLibrary("TasselBlas") and declares six native methods. The JNI glue is in the repository as C source, with no compiled binary for Arm64.

Inside the dependency JAR files – This group is visible neither in your source nor in your dependency declarations. The assessment resolved the dependency tree and inspected the binaries inside each archive:

$ unzip -l cisd-jhdf5-19.04.1.jar | grep native
native/jhdf5/amd64-Linux/libjhdf5.so
native/jhdf5/arm-Linux/libjhdf5.so

$ file native/jhdf5/*/libjhdf5.so
amd64-Linux: ELF 64-bit LSB shared object, x86-64
arm-Linux: ELF 32-bit LSB shared object, ARM, EABI5

Note the second directory: it is 32-bit ARM, not aarch64. In a listing it reads as ARM support, but on Graviton the architecture-keyed loader finds no match, and no published release contains an aarch64-Linux directory. Two further dependencies arrived the same way: cisd:base:18.09.0 through jhdf5, and gov.nih.nlm.ncbi:ngs-java:2.9.0 through com.github.samtools:htsjdk:2.24.1, whose loader publishes linux-x86_64 only.

Remediate the findings

In this step, you hand the findings to the remediation skill and review the change it produces.

To remediate the findings

  1. Collect the finding IDs as the comma-separated list that --ids expects:
    atx ct findings list --repo graviton-demo::tassel-renovate --json \
    | jq -r '[.[].id] | join(",")'

  2. Pass that list to the remediation:
    atx ct remediation create --ids <finding-ids> --local

  3. Enter atx ct remediation status --id <remediation-id> to follow it.
  4. Review the branch it produced with git log and git diff --stat.

Note what you do not pass: neither the transformation nor the repository. Each finding already records the transformation that resolves it, so the remediation reads that from the findings and derives the target repositories from them. Pass --transformation-name only to pin or override that choice.

The run produced three atomic commits (the analysis reports, the change itself, then the validation reports):

build.gradle.kts | 53 ++++-
.../matrixalgebra/Matrix/DoubleMatrixFactory.java | 7 +-
graviton-analysis/ (8 report files)
graviton-validation/ (6 report files)
15 files changed, 867 insertions(+), 3 deletions(-)

Of the 867 lines added, only two files are code that runs. The remainder documents what was found and what was done.

What the remediation changed

1. It removed the x86-only dependency from the resolved classpath. The ngs-java artifact downloads linux-x86_64 native libraries at runtime and has no aarch64 search path. There is no aarch64-capable ngs-java 2.x to upgrade htsjdk to, so the remediation excluded the unused code path and recorded why:

// gov.nih.nlm.ncbi:ngs-java (transitive via htsjdk) downloads the NCBI
// ngs-sdk/ncbi-vdb natives at runtime. Those are linux-x86_64 only.
// TASSEL only uses htsjdk's pure-Java SAM/BAM/CRAM/VCF readers, so the
// unused SRA path is excluded rather than bumping htsjdk (no
// aarch64-capable ngs-java 2.x exists).
configurations.all {
    exclude(group = "openchart", module = "openchart")
    exclude(group = "gov.nih.nlm.ncbi", module = "ngs-java")
}

It then verified the exclusion took effect:

$ ./gradlew dependencies --configuration runtimeClasspath | grep -c ngs-java
0

2. It added an aarch64 native library path, ahead of the x86 payloads bundled in the JAR files. No aarch64 build of jhdf5 or cisd:base is published, and their C sources are not in the repository, so they cannot be recompiled there. The remediation added a resolution order for externally built binaries:

val tasselNativeLibDir: String =
    (project.findProperty("tasselNativeLibDir") as String?)
        ?: System.getenv("TASSEL_NATIVE_LIB_DIR")
        ?: file("src/main/native/aarch64").absolutePath

val isAarch64: Boolean = System.getProperty("os.arch").lowercase().let {
    it == "aarch64" || it == "arm64"
}

3. It applied Graviton JVM flags and wired the native path into the runtime. The test block previously set only -Xmx10g:

test {
    // -Xmx10g is architecture-neutral. The code-cache sizing flags below are the
    // Graviton (ARM64) tuning recommended for JDK 21; both are valid on x86-64 too.
    jvmArgs = listOf<String>(
        "-Xmx10g",
        "-XX:ReservedCodeCacheSize=64M",
        "-XX:InitialCodeCacheSize=64M"
    )
    if (isAarch64 && file(tasselNativeLibDir).isDirectory) {
        systemProperty("java.library.path", tasselNativeLibDir)
        systemProperty("native.libpath", tasselNativeLibDir)
    }

4. It made the state of the native libraries visible at build and run time. The build now warns on an Arm64 host when the aarch64 directory is missing, naming the libraries to supply. At the native load site, which previously logged the same message on every platform, the architecture is now included:

-	myLogger.info("TasselBlas library for system-specific BLAS/LAPACK not found. "
-			+ "Using system-independent EJML for DoubleMatrix operations.");
+	myLogger.info("TasselBlas library for system-specific BLAS/LAPACK not found for os.arch="
+			+ osArch + ". Using system-independent EJML for DoubleMatrix operations. To use"
+			+ " native BLAS on this architecture, place a matching libTasselBlas.so on"
+			+ " java.library.path.");

Together, these changes give the project a defined place for aarch64 binaries ahead of the bundled x86 ones, apply the Graviton JVM tuning, and report the state of those libraries at build and run time.

Validate the build on Arm64

In this step, you confirm the change compiles on the target architecture, which the remediation does for you on an Arm64 host.

To validate the build

  1. Check out the branch the remediation created.
  2. Enter ./gradlew clean build -x test --no-daemon.
  3. Confirm the output reports a successful build and produces the JAR file.
    BUILD SUCCESSFUL in 14s
    5 actionable tasks: 5 executed
    
    $ ls -la build/libs/sTASSEL.jar
    -rw-r--r-- 3681163 build/libs/sTASSEL.jar
    
    $ ls build/libs/lib/*.jar | wc -l
    61

The JAR file is produced and 61 dependency JAR files resolve.

Deploy to a Graviton instance and verify

This step is outside AWS Transform, as Figure 1 shows. Arm64 is not a single platform: macOS and Linux on aarch64 differ in exactly the dimension that matters here, which native binaries exist. The remediation ran locally, so the change is already on disk and ready to carry onto an instance.

To deploy and verify on Graviton

  1. Launch a c7g.2xlarge instance running Amazon Linux 2023.
  2. Install Amazon Corretto 21, OpenBLAS, and LAPACK as aarch64 packages.
  3. Copy the remediated repository to the instance.
  4. Build it on the instance with ./gradlew classes copyDependencies.
  5. Compile the native BLAS bridge for aarch64. Its C source includes a macOS-only header, so first change #include <vecLib/cblas.h> to #include <cblas.h>, then run:
    gcc -O3 -shared -fPIC -I"$JAVA_HOME/include" -I"$JAVA_HOME/include/linux" \
    -I/usr/include/openblas -o libTasselBlas.so <jni-source>.c \
    -lopenblas -llapack -lm

  6. Run the application and confirm the native library loads.

The build resolves 62 dependency JAR files on the instance. The file command confirms the native library is built for the target architecture:

libTasselBlas.so: ELF 64-bit LSB shared object, ARM aarch64

Running the application on the instance:

os.arch : aarch64
java.vendor : Amazon.com Inc. (Corretto 21)
libTasselBlas : LOADED
DoubleMatrix backend: blas
fast path active : YES (native BLAS/LAPACK)

matmul 512x512 best 12.47 ms | 21.53 GFLOP/s

The native library loads, the BLAS backend is selected, and the matrix algebra runs. The application works on Graviton: the same application and the same JVM, now on Arm64.

It is also faster. In our testing on this c7g.2xlarge instance, the same operation took 60.36 ms on the pure-Java path and 12.47 ms with the native library, roughly five times the throughput. Those two numbers compare the native and pure-Java paths on Graviton rather than Graviton against x86. They are the reason to rebuild the native libraries rather than work around them.

Scale across your portfolio

In this step, you extend the same analysis across a source and put it on a cadence, using AWS Transform-managed infrastructure.

To analyze a portfolio on a recurring schedule

  1. Analyze every repository in a source:
    atx ct remote analysis --type graviton-readiness --mode aws-managed \
    --sources graviton-demo

  2. Create a schedule so the analysis repeats:
    atx ct schedule create --name graviton-weekly --mode aws-managed \
    --execution-role <role-arn> --recurrence weekly:MONDAY \
    --type graviton-readiness --sources graviton-demo

A single submission can include up to 5,000 repositories. Schedules that run on AWS Transform-managed infrastructure need an execution role that AWS Transform assumes on each run. For how to configure it, refer to Execution role for AWS Transform-managed schedules. For how analysis and remediation are billed, refer to AWS Transform pricing.

Clean up

The Graviton-based instance incurs ongoing charges while it runs, and a recurring schedule incurs charges on every run. To avoid them, terminate the instance when you are finished:

aws ec2 terminate-instances --instance-ids <instance-id>

If you created a recurring schedule, delete it with atx ct schedule delete. The source connection and the analysis and remediation records carry no ongoing cost. To remove them, use atx ct remediation delete, atx ct analysis delete, and atx ct source remove.

Conclusion

In this post, you learned how to get a Java application ready for AWS Graviton with AWS Transform continuous modernization. The readiness assessment surfaced Arm64-incompatible native libraries that were not declared anywhere in the project. The remediation skill resolved them in code, in three atomic commits touching two files, and validated the build on Arm64. You then deployed the result to a Graviton instance yourself, where the application ran using its native BLAS library.

The readiness assessment is read-only, so you can point it at all the repositories within your source and see where your estate stands before changing anything. To get started, open the AWS Transform console and run a Graviton readiness analysis, or install the CLI and run the commands in this post.

For more information about the command surface, refer to Working with continuous modernization in the AWS Transform User Guide. For instructions on getting started with AWS Transform, refer to Setting up AWS Transform. For pricing details, refer to AWS Transform pricing.

For a related walkthrough using the interactive transformation, refer to Migrating your Java applications to AWS Graviton using AWS Transform custom. For guidance on tuning workloads after you migrate, refer to the AWS Graviton Technical Guide.


About the authors

Harvinder Nagpal

Harvinder Nagpal

Harvinder is a Sr. Specialist on the Agentic AI team at AWS. He focuses on the Agentic AI Developer Experience portfolio and helps customers take Agentic AI to production. He works with AWS field teams and Partners on GTM strategy and executive conversations, and he passes customer feedback to product teams. He spent 15+ years in identity, access management and cybersecurity, so he helps customers build security, governance and compliance into Agentic AI from the start.

Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan is a Principal Specialist Solutions Architect at AWS. He leads generative AI initiatives that focus on Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation.

Varun Kulkarni

Varun Kulkarni

Varun is a Senior Product Manager–Technical at AWS working on AWS Transform custom and continuous modernization, which use agentic AI to help developers modernize code across their entire portfolio. Varun focuses on helping customers modernize their applications faster and keep them current over time.

How BMW Group accelerated connected vehicle workloads on AWS Graviton

Post Syndicated from Tomislav Lozančić original https://aws.amazon.com/blogs/architecture/how-bmw-group-accelerated-connected-vehicle-workloads-on-aws-graviton/

This post is co-written with Tomislav Lozancic, Hrvoje Lukavski from BMW Group, and Hugo Cardoso from CTW.

BMW Connected Company, a division within BMW Group, develops and operates premium digital services for BMW’s connected vehicle fleet of more than 24.5 million vehicles worldwide. Critical TechWorks (CTW), established in September 2018, focuses exclusively on developing software for BMW Group’s future connected vehicle fleet.

In 2024, BMW Connected Company began migrating its Connected Vehicle platform, known internally as Orbit, from x86 to Arm-based compute as part of a broader modernization strategy to advance BMW Group’s economic and environmental goals.

In this post, we share the methodology behind the migration, tooling and patterns that helped application teams move to AWS Graviton at their own pace, without service disruption.

Laying the groundwork

Before applications could adopt a new processor architecture, the platform needed a more flexible provisioning layer. The team adopted Karpenter, replacing fixed Managed Node Groups with dynamic, policy-driven node pools that could provision the right instance type automatically. You can read more about this migration in Transforming the BMW Connected Vehicle Backend with Karpenter.

With the compute foundation in place, the next challenge was supporting multi-architecture builds. Building, testing, and deploying the same application for two architectures without slowing teams down required extending the continuous integration and continuous delivery (CI/CD) platform. Build runners needed to target both x86 and Arm while producing dual build pipelines, as described in the following section.

Introducing Graviton-based CI/CD runners

The Connected Vehicle CI/CD platform facilitates over 130,000 builds and deployments daily through self-hosted GitHub Actions runners. You can read more about the evolution of this platform in An Engine of Efficiency: BMW Group’s CI/CD Modernization Journey with AWS.

To surface potential issues early and minimize disruption, the team first validated Graviton on a set of self-contained services. Dedicated Graviton runners operated alongside the existing x86 fleet during this phase. The price-performance advantage of Graviton was confirmed immediately, with lower cost per build minute and faster build times, justifying the business case for wider adoption.

Building on these initial results, the team designed the wider platform rollout around two complementary tracks.

  1. Dual build pipelines: Building and shipping both CPU architectures in parallel, giving applications a non-disruptive path to transition independently.
  2. Container hosting: Extending support into the centralized container platform, so applications could be hosted on Graviton.

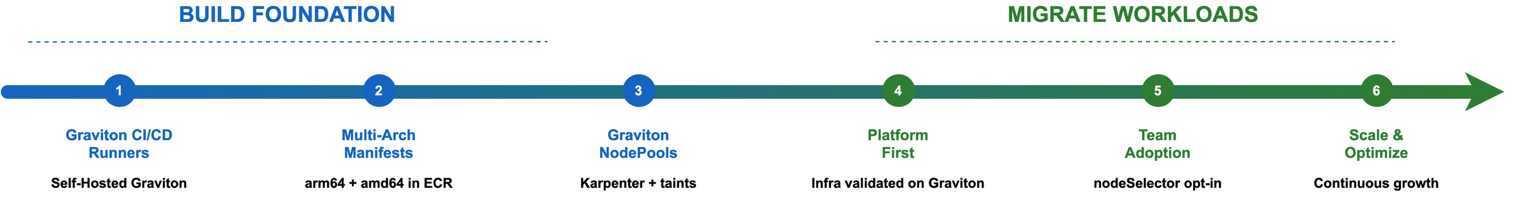
The following figure shows the six-stage journey to adopt AWS Graviton. The stages are grouped into two phases: a build-foundation phase and a workload-migration phase.

Six-stage AWS Graviton adoption journey grouped into a build-foundation phase and a workload-migration phase

Figure 1: AWS Graviton adoption journey across the Connected Vehicle platform

Supporting adoption

Getting teams onto Graviton depended less on policy than on removing friction. The following practices lowered the barrier to entry, beginning with the build pipeline.

1 – Multi-architecture builds

As outlined earlier, every container image needed to support both architectures before workloads could run on Arm-based instances. To achieve this, two complementary build approaches were used: emulated builds using Docker Buildx with QEMU, and native builds on Graviton-based runners.

Both approaches produce multi-arch images by publishing a manifest list (OCI image index) alongside the architecture-specific images. When a container runtime pulls a tagged image, it reads the manifest and automatically selects the correct variant for the node’s architecture. This means a single image tag serves both arm64 and amd64 nodes transparently.

2 – Mirroring base images

Public images are mirrored into a private Amazon Elastic Container Registry (Amazon ECR) to achieve availability, immutability, and CVE compliance. To preserve multi-arch support during mirroring, the team uses Google’s Crane. Crane transfers images directly between registries and filters the manifest to only the required platforms, which avoids wasted storage from unused architectures.

Besides public images, custom application workloads also needed support for both architectures. Most Dockerfiles required no changes, because their base images and dependencies already supported multiple architectures. In some cases, an alternative or dependency with Arm support needed to be found. For the builds, two approaches were considered:

  1. Native build per architecture: Each architecture is built and pushed separately on a runner with the matching architecture, followed by a final job that creates and pushes the image index. In GitHub Actions, this means one runner per architecture plus one index-creation step. This approach is more reliable but requires a dedicated runner for each target architecture.
  2. Emulated builds from a single machine: Using Docker Buildx with QEMU, all architectures can be built and pushed from a single x86 or Arm runner. This streamlines the pipeline but introduces emulation overhead, often making builds significantly slower for compute-intensive workloads.

The team opted to support both approaches. For platform-scale adoption, Graviton runners were preferred because they ran arm64 builds natively. This avoided the QEMU emulation overhead and surfaced architecture-specific issues earlier in the pipeline. With GitHub Actions reusable workflows, teams can select the right fit for each use case. Dockerfiles use the QEMU path to avoid spinning up additional runners. Those with significant complexity, large dependency downloads, or long build times use native builds, where the overhead becomes problematic.

Graviton runner labels mirror the existing x86 labels, so adoption involves swapping x64 for arm64 in a single label.

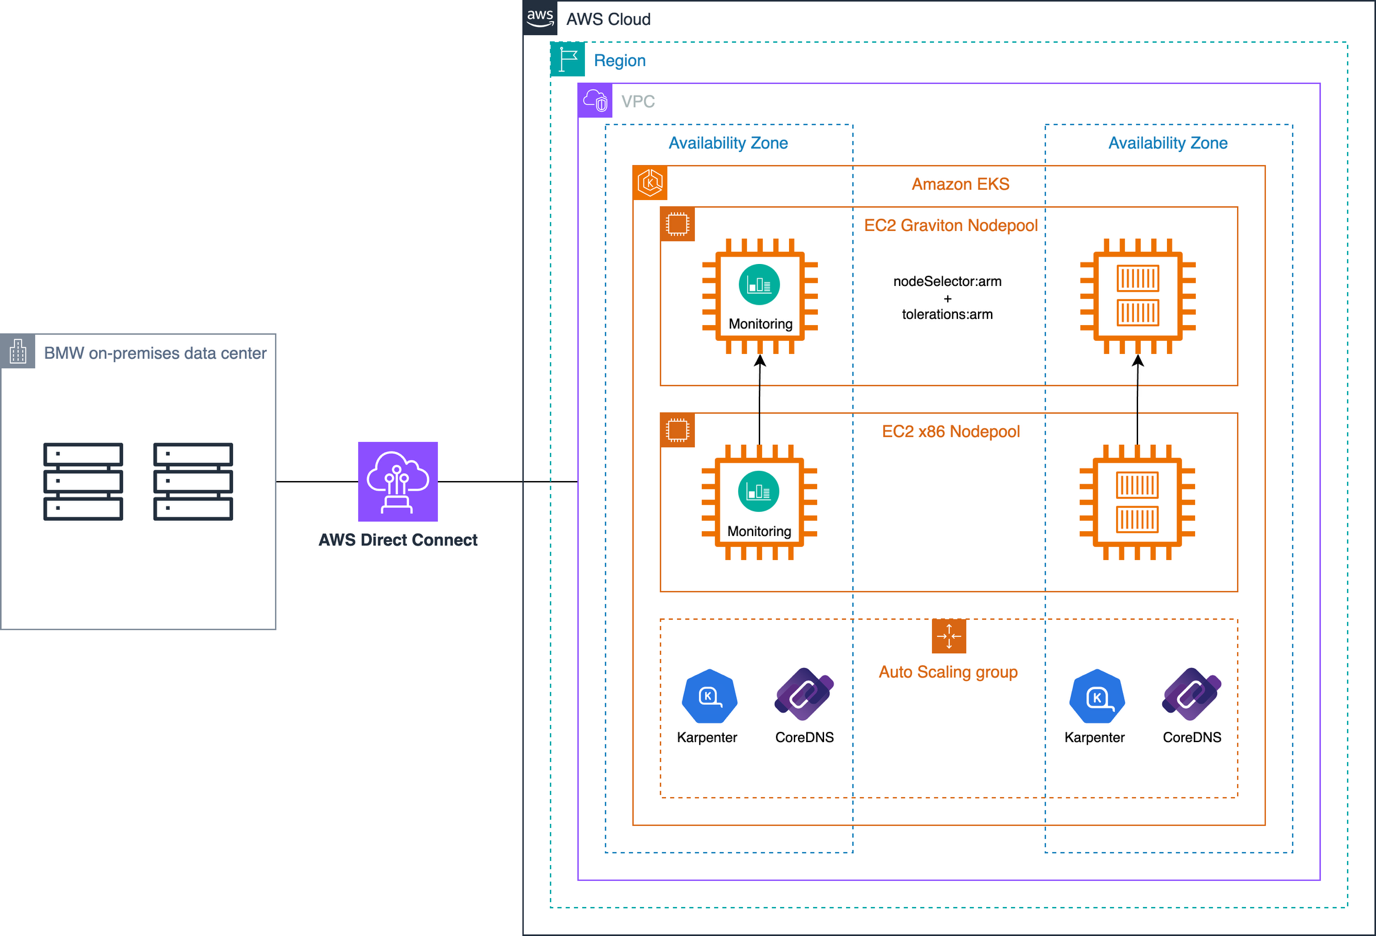
3 – Defining Graviton NodePools

The following diagram shows the mixed-architecture Amazon Elastic Kubernetes Service (Amazon EKS) cluster, including how on-premises systems connect and how the Graviton and x86 node pools coexist.

Mixed-architecture Amazon EKS cluster showing on-premises connectivity and coexisting Graviton and x86 node pools

Figure 2: Mixed-architecture Amazon EKS cluster with dedicated Graviton node pools and opt-in scheduling

Dedicated Graviton node pools let teams adopt without friction across each environment. The pools are shared and general-purpose by default, not tailored to individual workloads. This keeps the underlying infrastructure model consistent and predictable while still allowing teams to migrate on their own schedule. Karpenter’s automatic scaling foundation supports efficient resource allocation and rapid provisioning for both Arm and x86 workloads.

To avoid accidental scheduling, the Graviton node pools use taints. Workloads must explicitly opt in using a node selector and matching toleration. This supports controlled rollout and predictable behavior:

nodeSelector:
  bmw.de/stateless-arm: supported

tolerations:
- key: "bmw.de/stateless-arm"
  operator: "Equal"
  value: "supported"
  effect: "NoSchedule"

With this in place, only Arm-ready workloads are scheduled on Graviton nodes, while other workloads continue to run on amd64 nodes without disruption.

4 – Phased rollout

Before supporting broad adoption for application workloads, the team first validated the migration path by running core platform services (Karpenter, Prometheus, and operational tooling). This platform-first approach identified compatibility gaps early, refined node pool configuration, and established rollback patterns. Teams had a proven reference model before they were encouraged to opt in.

A key design principle was minimizing rollback risk by keeping both architectures viable simultaneously. Dual-arch images and a dedicated NodePool mean every application can run on both CPU architectures. If issues arise, workloads fall back to x86 without image rebuilds or pipeline changes.

Kubernetes node affinity rules prefer Arm without forcing it, so workloads naturally gravitate toward Graviton instances:

{{/*
Workload node affinity
*/}}
{{- define "common.nodeaffinity" -}}
preferredDuringSchedulingIgnoredDuringExecution:
- weight: 100
  preference:
    matchExpressions:
    - key: kubernetes.io/arch
      operator: In
      values:
      - arm64
{{- end -}}

{{/*
Workload node tolerations
*/}}
{{- define "common.tolerations" -}}
- key: bmw.de/arm
  operator: Equal
  value: supported
  effect: NoSchedule
{{- end -}}

If a full rollback is needed, the GitOps-based ArgoCD deployment model makes recovery straightforward by reverting to the previous version in Git and letting ArgoCD reconcile the cluster state.

Results

The migration delivered approximately $600,000 in annualized infrastructure savings and measurable performance improvements. After moving the NGINX-based ingress controller from x86 to Graviton, key results included:

  • CPU consumption decreased by approximately 57 percent, while maintaining the same ingress profile.
  • Price-performance improved by around 40 percent, as lower CPU consumption per request increased throughput capacity per dollar spent.
  • Scaling efficiency improved at peak loads, with workloads requiring less compute capacity to handle equivalent traffic volumes.

Today, more than 65 percent of the platform runs on Graviton across production environments, a shift that supports BMW Group’s sustainability goals by reducing compute energy demand.

Lessons learned

Migrating a platform of this scale surfaced practical lessons that shaped the team’s approach and would benefit others considering a similar transition:

  • Opt-in scheduling: Use taints, selectors, and tolerations to make sure that only ready workloads migrate.
  • Multi-architecture images: One manifest-based tag for both architectures keeps releases straightforward and rollback instant.
  • Platform-first adoption: Validate on shared infrastructure first to reduce risk before teams opt in.
  • Optimization of emulated builds: This approach is useful for straightforward pipelines. Compute-heavy builds should use native or cross-compilation paths instead, which avoids unnecessary QEMU overhead and long build times.

Conclusion

BMW Group migrated its Connected Vehicle platform to AWS Graviton, achieving over $600,000 in annual cost savings and a 40 percent improvement in price-performance. The more than 130,000 daily builds and deployments that power more than 24.5 million connected vehicles continued without disruption.

The migration succeeded because of deliberate, incremental choices: taint-based node isolation, multi-arch container builds, and Karpenter’s ability to provision the right instance at the right time. Each layer reduced risk while keeping the rollout optional for individual teams. What started as a platform experiment is now the default compute path.

To get started with Graviton-based workloads on Amazon EKS, see the AWS Graviton Getting Started guide. To learn how BMW Group adopted Karpenter at scale, read Transforming the BMW Connected Vehicle Backend with Karpenter.


About the authors

Tomislav Lozančić

Tomislav Lozančić

Tomislav is Lead Cloud Solution Architect at BMW Group, responsible for the Connected Vehicle platform overseeing more than 400 Amazon EKS clusters supporting 24.5+ million connected vehicles. With a degree in Computer Science, he specializes in cloud-native technologies and Kubernetes at scale. Tomislav focuses on optimizing cloud infrastructure for performance, cost efficiency, and reliability, playing a key role in BMW Group’s cloud strategy and mission-critical services.

Brendan Jones

Brendan Jones

Brendan is a Senior Solutions Architect at AWS for BMW Group. He is passionate about helping automotive customers build innovative, highly scalable, and resilient cloud architectures which maximize business impact for their customers.

Akshay Gupta

Akshay Gupta

Akshay is a Cloud Infrastructure Architect at AWS with over 14 years of experience in designing and implementing scalable, secure, and cost-efficient cloud solutions. He leads cloud transformation initiatives across multiple industries, helping customers modernize their infrastructure and optimize cloud operations. Akshay specializes in DevOps automation, FinOps strategies, and infrastructure-as-code frameworks to drive efficiency and innovation. In his free time, Akshay enjoys contributing to the cloud and DevOps community through technical writing, open-source projects, and mentoring professionals in their cloud journey.

Hrvoje Lukavski

Hrvoje Lukavski

Hrvoje is Lead Product Manager at BMW Group, driving the development of the Connected Vehicle Platform and ensuring its quality and future-readiness. A FinOps Champion and Chaos Engineering pioneer, he advises executive leadership on cloud strategy and believes the best engineering disappears into the product.

Hugo Cardoso

Hugo Cardoso

Hugo is a DevOps Engineer at Critical TechWorks. With a background in software engineering, he applies a developer’s mindset to platform and infrastructure challenges by connecting systems and extending them with software when needed. He focuses on breaking down complex problems while maintaining strong security and tenancy boundaries, delivering solutions that keep platforms simple and intuitive for both their users and maintainers.

Vessel-specific voyage optimization with machine learning: Manta on AWS

Post Syndicated from Borja Rojo original https://aws.amazon.com/blogs/architecture/vessel-specific-voyage-optimization-with-machine-learning-manta-on-aws/

Voyage performance varies even between seemingly identical ships, and models built on vessel-type averages often miss the mark. Manta Marine Technologies (Manta) closes that gap with machine learning (ML) models trained on each vessel’s own operational history. In this post, we show how Manta delivers vessel-specific voyage optimization with machine learning on Amazon Web Services (AWS), helping shipowners reduce fuel consumption and improve voyage efficiency.

Differences in hull condition, trim, draft, machinery condition, loading patterns, and operational practices mean that when operators build models on vessel-type averages, those models often can’t capture how a specific vessel performs. For shipowners, this gap translates directly into unnecessary fuel consumption and cost.

Manta takes a vessel-specific approach. The company trains machine learning models on each vessel’s own operational history and combines them with forecast weather and ocean conditions. To support this approach at scale, Manta built its data infrastructure on AWS. Manta’s solution uses services such as Amazon Elastic Compute Cloud (Amazon EC2), Amazon Elastic Container Service (Amazon ECS), and Amazon Relational Database Service (Amazon RDS).

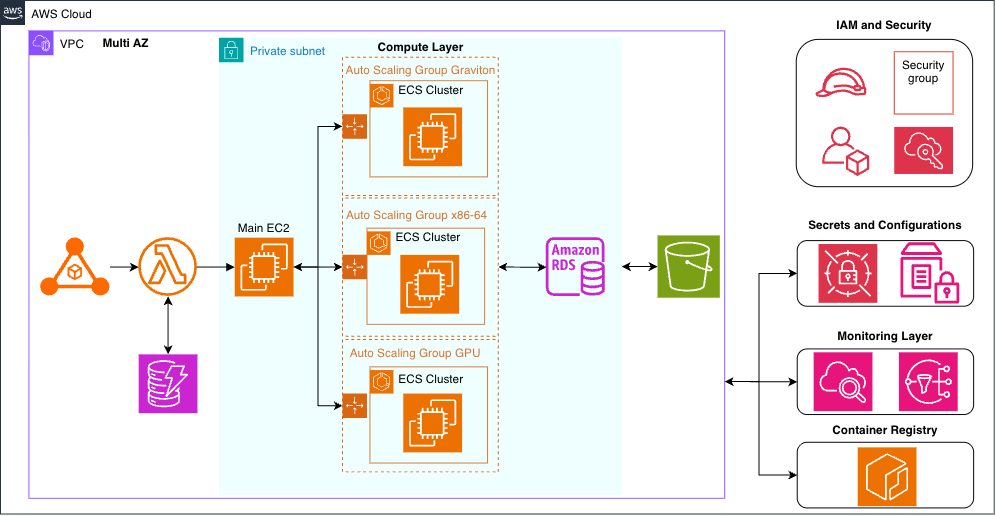
The following diagram shows the architecture of the Manta data infrastructure on AWS. The system receives vessel data and environmental forecasts in a secure, multi-Availability Zone environment. Manta’s solution processes this data, stores it, and uses it to train and run machine learning models.

Manta’s AWS data infrastructure: vessel data flows through a VPC for processing, storage, and ML model training

Figure 1: Architecture of Manta’s data infrastructure on AWS

In the diagram, vessel data and environmental forecasts enter an Amazon Virtual Private Cloud (Amazon VPC) deployed across multiple Availability Zones. Inside the VPC, Manta uses Apache Airflow on Amazon EC2 to orchestrate data pipelines and machine learning workloads as Amazon ECS tasks on EC2 capacity, with a separate Auto Scaling group and capacity provider for each instance type. AWS Lambda serves as the entry point for requests from client applications. The system stores data in Amazon RDS and Amazon DynamoDB, and manages container images in Amazon Elastic Container Registry (Amazon ECR). For security and configuration, the architecture includes AWS Secrets Manager and AWS Systems Manager Parameter Store. The Airflow scheduler also drives the retraining loop: as new voyage data accumulates for a vessel, it launches a training task on the appropriate instance type, and the updated model is used for that vessel’s subsequent voyage optimizations. Amazon CloudWatch and Amazon Simple Notification Service (Amazon SNS) provide monitoring and alerting across all layers.

The challenge: Predicting how a specific vessel performs

Manta’s goal is voyage guidance that continuously learns from each vessel’s behavior and improves over time. This requires infrastructure that processes large volumes of operational vessel data—up to 3 billion data points in a single training run. The infrastructure also combines historical performance with weather and ocean forecasts. Manta’s solution must also run machine learning workflows, deliver guidance globally, and support continuous model improvement as new voyage data arrives.

The solution: A cloud-native data infrastructure built on AWS

Manta runs its data infrastructure as a cloud-native solution on AWS, deployed across multiple Availability Zones within an Amazon VPC.

At the core of the infrastructure, workflow orchestration with Apache Airflow runs on Amazon EC2. Airflow runs on a persistent EC2 instance because the orchestration layer needs a long-running server process. Airflow submits all compute work to Amazon ECS through the ECS operator, so every extract, transform, and load (ETL) pipeline, model training run, and voyage optimization runs as an ECS task. Manta runs those tasks on EC2 capacity rather than AWS Fargate because EC2 gives the team direct control over instance type, including GPU instances and specific chip generations. Manta defines one capacity provider, one Auto Scaling group, and one launch template per instance type instead of sharing a single pool. Model training and voyage optimization use different instance types. Per-instance-type capacity gives granular control over how each workload scales, running less urgent jobs on Spot capacity and time-sensitive jobs On-Demand. The infrastructure also uses AWS Lambda as the entry point for requests from client applications. A Lambda function triggers the corresponding Airflow directed acyclic graph (DAG) or returns already-processed results from the database. Manta manages container images in Amazon ECR, with separate images for Graviton and x86-64 instances, GPU workloads, orchestration, and machine learning operations. Manta stores data in Amazon RDS and Amazon DynamoDB.

For observability, Manta uses Amazon CloudWatch for monitoring and Amazon SNS for alerting. Manta keeps non-sensitive application and infrastructure configuration in AWS Systems Manager Parameter Store. For sensitive values such as database connection credentials, Airflow application secrets, and authentication tokens for third-party services, Manta uses AWS Secrets Manager. Those secrets are encrypted, and access to them is restricted through IAM permissions. Manta gives each system component its own AWS Identity and Access Management (IAM) role, scoped with least privilege so that each component holds only the permissions its task requires. The company also encrypts data with AWS Key Management Service (AWS KMS).

Because the infrastructure runs in the cloud, Manta continuously improves its models as new voyage data becomes available. Each completed voyage contributes operational data to future model training, and an Airflow scheduler retrains each vessel’s model periodically, based on how much new data that vessel has produced. This creates a learning cycle that makes recommendations increasingly relevant for that specific vessel.

Why AWS

With AWS, Manta has the scalability to support growing fleets and increasing data volumes. The company stores historical vessel performance data, processes weather and ocean forecasts, and trains and operates its machine learning models. It also delivers voyage recommendations to fleets operating worldwide and scales compute capacity on demand as workloads grow.

Cost efficiency is also a key factor. Manta runs its ETL pipelines, model training, and voyage optimization workloads on AWS Graviton-based instances. For one ETL pipeline that processes large datasets, Manta observed approximately 25–30 percent better price performance after moving to Graviton-based instances. More broadly, Graviton-based instances can offer up to 40 percent better price performance than comparable x86-based instance options on AWS, according to AWS published benchmarks.

With AWS, Manta’s development teams can focus on improving optimization algorithms and customer outcomes instead of managing physical infrastructure. Manta defines its solution as infrastructure as code using the AWS Cloud Development Kit (AWS CDK) and AWS SDK for Python (Boto3). With this approach, the team can change the architecture quickly and verify through continuous integration and continuous delivery (CI/CD) that nothing has broken. It can also reproduce identical development, staging, and production environments.

That reproducibility also changes how the team experiments. Manta’s engineers develop and validate machine learning and data engineering work on their own machines, against large samples of vessel data pulled from the system. The only cost of an experiment is then retrieving the data. Because that work runs in the same container images the system uses in production, a validated algorithm reaches the full fleet without re-engineering and without infrastructure to provision. When an experiment outgrows a local machine, the team runs it at full scale on AWS instead of scoping it down. They submit the same container to the instance type the workload needs, whether that means GPU capacity or many parallel CPU tasks. Experimentation stays cheap when it can be and unconstrained when it needs to be. Scaling a validated result to every vessel is then a scheduling decision rather than a project.

The results: Guidance built around how each vessel actually performs

Through Manta’s solution, ship operators receive voyage-specific guidance built on the vessel’s own historical performance and relevant external data such as atmospheric and oceanic weather data. The system’s continuous improvement loop refines this guidance as new voyage data arrives, with each vessel’s model retrained as its own operational history grows.

Fleet managers gain guidance designed around how each vessel actually performs, rather than vessel-type averages or industry benchmarks. Pairing vessel-specific data with decades of maritime operational expertise helps customers run greener and more profitable operations.

Based on internal voyage simulations conducted across its active fleet, Manta expects fuel savings of approximately 2–4 percent per vessel. The company anticipates further gains as its models improve and new capabilities are added.

Conclusion

Manta built a cloud-native data solution on AWS to deliver vessel-specific voyage optimization. Apache Airflow on Amazon EC2 orchestrates data pipelines and machine learning workloads across EC2, Amazon ECS, and AWS Lambda. Manta stores data in Amazon RDS and Amazon DynamoDB and enforces security through least-privilege IAM roles and AWS KMS. Graviton-based instances keep the solution cost efficient as data volumes grow. Every completed voyage feeds a learning cycle that makes guidance increasingly tailored to each vessel.

To learn more about Manta’s voyage optimization solution, visit the Manta Marine Technologies website. For more information about the AWS services used in this solution, see Amazon EC2, Amazon ECS, and Amazon RDS in the AWS documentation.

For related reading, see Using machine learning to predict vessel time of arrival with Amazon SageMaker and How potential performance upside with AWS Graviton helps reduce your costs further.


About the authors

Borja Rojo

Borja Rojo

Borja is Lead Data Scientist at Manta Marine Technologies, where he leads the development of the company’s data infrastructure and machine learning capabilities. He holds a PhD in aerothermal dynamics and brings 10 years of experience in digital twins, simulation, and IT infrastructure from the automotive, telecom, and healthcare industries, with expertise in optimization and machine learning. Outside work, he enjoys climbing and playing football, and when time allows, tending his bee hives.

Gonzalo Montero Villar

Gonzalo Montero Villar

Gonzalo, PhD, is a senior machine learning engineer at Manta Marine Technologies, where he works on the development of the infrastructure, the ML models and algorithms used by the data science department’s products and services.

Harkamal Singh

Harkamal Singh

Harkamal is a Senior Cloud Engineer with strong experience in designing and delivering scalable, secure, and reliable cloud infrastructures. He works extensively with AWS, DevOps, infrastructure as code, data platforms, containers, serverless technologies, networking, and cloud automation. His experience includes building and operating cloud-native solutions with services such as Amazon ECS, AWS Lambda, Amazon S3, Amazon RDS, Amazon DynamoDB, AWS IoT Core, and Amazon CloudFront, with a strong focus on reliability, security, observability, and cost efficiency. Outside work, he enjoys travelling, exploring new places, and spending time with family and friends.

Mario Troiano

Mario Troiano

Mario is a Cloud Sales Representative at AWS, where he helps customers across SMB and ISV segments grow and use the full power of AWS solutions in a cost-efficient way. He has worked on several AI/ML projects related to forecasting, AI conversational interfaces, and process automation. Outside work, Mario enjoys playing football and tennis, and taking long road trips across Spain.

All the numbers: Amazon Prime Day 2026 powered by AWS

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/all-the-numbers-amazon-prime-day-2026-powered-by-aws/

Amazon Prime Day 2026 was exclusively for Prime members and ran June 23–26, 2026 with millions of deals across more than 35 categories.

As part of our annual tradition of sharing how AWS powered Prime Day (2016, 2017, 2019, 2020, 2021, 2022, 2023, 2024, and 2025), I want to share the services and chart-topping metrics from AWS that made your amazing shopping experience possible.

Prime Day 2026 – all the numbers

As always, Prime Day was powered by AWS. Here are some of the most interesting and/or mind-blowing metrics:

Amazon Elastic Compute Cloud (Amazon EC2) and AWS Graviton – During Amazon Prime Day 2026, AWS Graviton powered up to 49% of the Amazon EC2 compute used by Amazon.com.

Amazon Elastic Block Store (Amazon EBS) – During Prime Day 2026, Amazon EBS, our high-performance block storage service, peaked at over 24.8 trillion I/O operations, moving over an exabyte of data daily.

AWS Lambda – AWS Lambda handled over 2.3 trillion invocations per day during Prime Day 2026.

Amazon Elastic Container Service (ECS) and Fargate – During Prime Day 2026, Amazon ECS launched an average of 158.3 million tasks per day on AWS Fargate, representing a 47.7 percent increase from the previous year’s Prime Day average.

Amazon CloudFront – Amazon CloudFront delivered over 2.1 trillion HTTP requests during the global week of Prime Day 2026, a 5 percent increase in total requests compared to Prime Day 2025.

Amazon DynamoDB – Amazon DynamoDB, a serverless, fully managed, distributed NoSQL database, powers multiple high-traffic Amazon properties and systems including Alexa, the Amazon.com sites, and all Amazon fulfillment centers. Over the course of Prime Day 2026, between June 23 and June 26, 2026, DynamoDB processed over 59 trillion requests. DynamoDB maintained high availability while delivering single-digit millisecond responses and peaking at 192 million requests per second.

Amazon Aurora – On Prime Day, Amazon Aurora, a relational database management system (RDBMS) built for high performance and availability at global scale for PostgreSQL, MySQL, and DSQL, processed hundreds of billions of transactions, stored 5,491 terabytes of data, and transferred 1,194 terabytes of data.

Amazon ElastiCache – During Prime Day, Amazon ElastiCache peaked at serving over 2.3 quadrillion daily requests and 2.1 trillion requests in a minute.

Amazon Kinesis Data Streams – Amazon Kinesis Data Streams, a fully managed serverless data streaming service, processed a peak of 988 million records per second during Prime Day 2026.

Amazon Simple Notification Service (SNS) – Amazon SNS, a fully managed pub/sub messaging service for application-to-application and application-to-person communication, delivered 5 trillion messages in a single day during Prime Day 2026.

Amazon Simple Queue Service (SQS) – Amazon SQS, a fully managed message queuing service for microservices, distributed systems, and serverless applications, received a peak of 213 million messages per second during Prime Day 2026

AWS CloudTrail – AWS CloudTrail processes billions of API activity events per day for governance, compliance, and operational auditing. During Prime Day 2026, that volume surged to 3.6 trillion events in just four days, a 44% increase over Prime Day 2025.

AWS CloudWatch – Amazon CloudWatch processed over 2.15 quadrillion metric observations per day during Prime Day 2026.

Amazon GuardDuty – During Prime Day 2026, Amazon GuardDuty monitored an average of 14.08 trillion log events per hour, a 59% increase from last year’s Prime Day.

AWS Fault Injection Service (FIS) – We ran over 44,000 AWS FIS experiments – more than six times what we conducted in 2025 – to help ensure Amazon.com remains highly available on Prime Day.

Prepare to scale

If you’re preparing for similar business-critical events, product launches, and migrations, I recommend that you take advantage of AWS Countdown Premium. From retail peak seasons to major sporting events, elections, and healthcare enrollment periods, we help you deliver flawless experiences when it matters most. Our experts help you manage your infrastructure to handle massive traffic spikes while maintaining security and performance. We work alongside your team to scale infrastructure, optimize costs during demand surges, strengthen security measures, and monitor real-time demands. To learn more, visit AWS Countdown Premium for business critical events.

I look forward to seeing what other records will be broken next year!

— Channy

Amazon EC2 R9g and R9gd instances powered by AWS Graviton5 processors are now generally available

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-ec2-r9g-and-r9gd-instances-powered-by-aws-graviton5-processors-are-now-generally-available/

Today, Amazon EC2 R9g and R9gd instances are generally available, powered by AWS Graviton5 processors. R9g instances are memory-optimized and deliver up to 25% better compute performance compared to Graviton4-based R8g instances, powered by the most energy efficient processor AWS has ever built.

R9g instances are ideal for memory-intensive workloads including databases, in-memory caches (Valkey, Redis, MemCached), real-time big data analytics, Linux-based workloads including containerized and micro-service-based applications (e.g. Kubernetes, Docker, EKS, ECS), as well as applications written in popular programming languages such as C/C++, Rust, Go, Java, Python, .NET Core, Node.js, Ruby, and PHP.

R9gd instances include local NVMe-based SSD block-level storage, ideal for memory-intensive workloads requiring fast, low-latency local storage such as open-source databases, distributed real-time big data analytics, large in-memory databases, and large caching workloads.

If you’re running workloads on R8g instances today, R9g gives you more performance per vCPU with faster memory, higher network and Amazon EBS bandwidth, and a larger L3 cache, all while using less energy.

What makes R9g different
Graviton5 processors bring several hardware improvements over Graviton4:

  • Up to 25% higher compute performance per vCPU
  • DDR5 8800 MT/s memory (up from 5600 MT/s in Graviton4), the fastest memory available in the cloud
  • 5x larger L3 cache for better data locality
  • Up to 2x higher network and EBS bandwidth for the largest instance sizes (up to 100 Gbps network, up to 72 Gbps EBS on the 48xlarge)
  • Up to 3x higher packet-processing performance

R9g and R9gd instances support Instance Bandwidth Configuration (IBC), which lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by 25%. This helps optimize performance for workloads with specific bandwidth requirements such as databases and caching.

All R9g and R9gd instances run on the AWS Nitro System, which offloads virtualization, storage, and networking to dedicated hardware. This gives your applications near-bare-metal performance while maintaining strong security isolation between instances.

R9g and R9gd instances feature the Nitro Isolation Engine (NIE), the same enhancement to the Nitro System introduced with C9g and M9g instances earlier this year, which enforces isolation of instances and harnesses formal verification to provide assurances of isolation with mathematical precision. Nitro Isolation Engine is a purpose-built component that is responsible for enforcing isolation between virtual machines, including mediation of all access to virtual machine memory, CPU register state, and I/O devices through a minimal set of APIs. Nitro Isolation Engine leverages formal verification, a technique to mathematically demonstrate that the hardware or software behaves as intended, and not just in specific test cases. This intensive verification technique establishes Nitro as the first formally verified cloud hypervisor, pioneering a new standard for mathematically proven cloud security. To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see the technical white paper.

EC2 R9g and R9gd instance specifications
R9g and R9gd instances are each available in 11 sizes, from medium to metal-48xl. The following tables show the full specifications for each size.

Instance size vCPUs Memory (GiB) Instance Storage Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
r9g.medium 1 8 EBS-Only Up to 15 Up to 12
r9g.large 2 16 EBS-Only Up to 15 Up to 12
r9g.xlarge 4 32 EBS-Only Up to 15 Up to 12
r9g.2xlarge 8 64 EBS-Only Up to 17 Up to 12
r9g.4xlarge 16 128 EBS-Only Up to 17 Up to 12
r9g.8xlarge 32 256 EBS-Only 17 12
r9g.12xlarge 48 384 EBS-Only 25 18
r9g.16xlarge 64 512 EBS-Only 34 24
r9g.24xlarge 96 768 EBS-Only 50 36
r9g.48xlarge 192 1536 EBS-Only 100 72
r9g.metal‑48xl 192 1536 EBS-Only 100 72

R9gd instances offer the same compute and networking performance as R9g, with the addition of local NVMe-based SSD storage for workloads that need fast, low-latency scratch space or temporary caches.

Instance size vCPUs Memory (GiB) Instance Storage (NVMe SSD) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
r9gd.medium 1 8 1 x 59 GB Up to 15 Up to 12
r9gd.large 2 16 1 x 118 GB Up to 15 Up to 12
r9gd.xlarge 4 32 1 x 237 GB Up to 15 Up to 12
r9gd.2xlarge 8 64 1 x 474 GB Up to 17 Up to 12
r9gd.4xlarge 16 128 1 x 950 GB Up to 17 Up to 12
r9gd.8xlarge 32 256 1 x 1900 GB 17 12
r9gd.12xlarge 48 384 3 x 950 GB 25 18
r9gd.16xlarge 64 512 1 x 3800 GB 34 24
r9gd.24xlarge 96 768 3 x 1900 GB 50 36
r9gd.48xlarge 192 1536 3 x 3800 GB 100 72
r9gd.metal‑48xl 192 1536 3 x 3800 GB 100 72

Getting started
You can launch R9g and R9gd instances from the Amazon EC2 console using any supported Arm-based AMI. R9g instances support Amazon Linux 2023, Amazon Linux 2, Ubuntu 22.04+, RHEL 8.4+, SUSE Linux Enterprise Server 15 SP3+, Debian 12+, and other major Linux distributions.

If you’re migrating from R8g, no code changes are required for most applications. Select the equivalent R9g instance size and your application runs with better performance. For containerized workloads, R9g works with Amazon EKS, Amazon ECS, and standard Kubernetes deployments. Multi-arch container images built for Arm64 run without changes.

Several resources help you get started: the AWS Graviton Getting Started Guide covers how to build, run, and optimize workloads on Graviton-based instances. The Graviton Savings Dashboard helps you track cost savings. AWS Transform automates code transformations for migrating Java applications from x86 to Graviton. To learn more, visit AWS Graviton Processors or Level up your compute with AWS Graviton.

Pricing and availability
Amazon EC2 R9g and R9gd instances are available in US East (N. Virginia, Ohio), US West (Oregon), and Europe (Frankfurt) Regions.

R9g and R9gd instances are available for purchase through Savings Plans, On-Demand, Spot Instances, Dedicated Instances, or Dedicated Hosts. For detailed pricing, visit the Amazon EC2 pricing page.

Ready to get started? Launch R9g instances from the Amazon EC2 console. For more details, visit the Amazon EC2 R9g instances page.

If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Share your feedback on AWS re:Post for Amazon EC2 or reach out through your usual AWS Support contacts.

— Daniel Abib

Happy 20th Birthday, Amazon EC2

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/happy-20th-birthday-amazon-ec2/

Twenty years ago today, Jeff Barr wrote a blog post that launched the Amazon EC2 Beta. That single post introduced resizable Linux virtual servers in the cloud, billed by the hour, with one instance type (m1.small) in one Region (US East). It was minimal yet useful, and it changed how the world thinks about computing infrastructure.
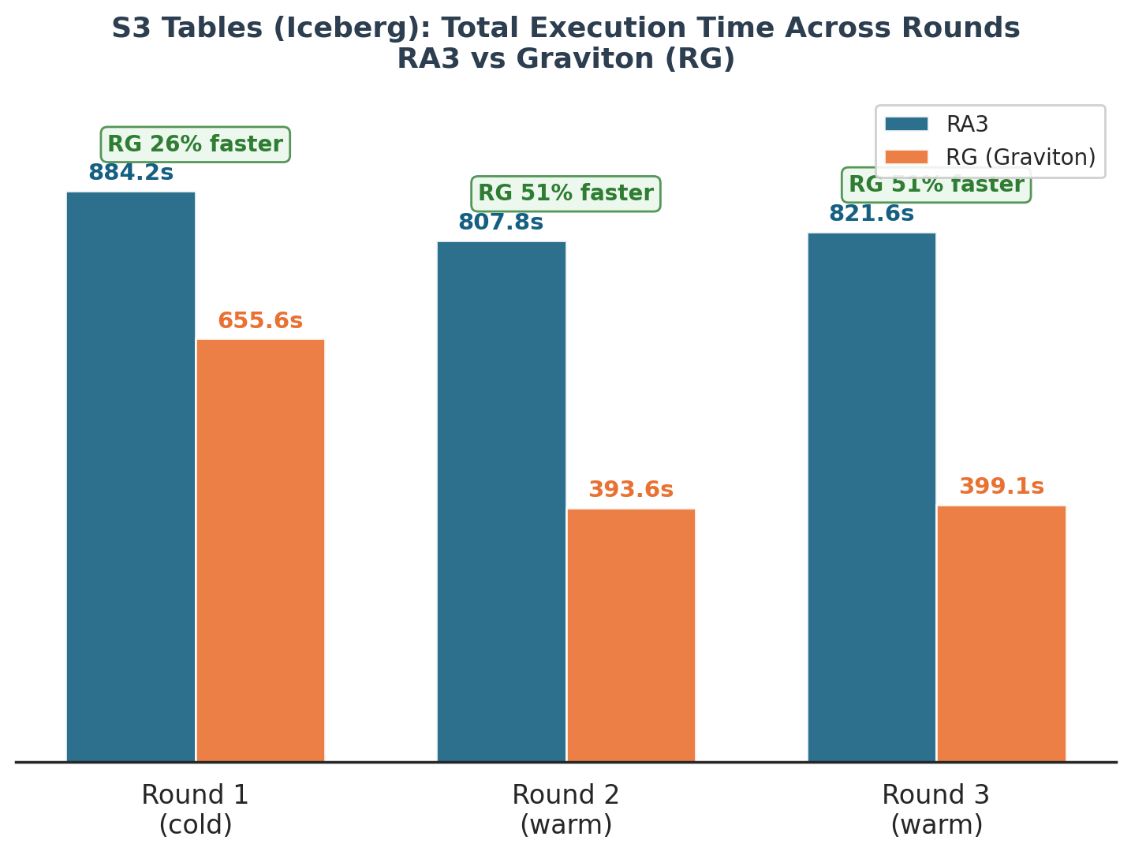
In 2021, Jeff covered the fifteen years of EC2 with the backstory and memorable EC2 launches. Over the last five years, AWS has continued to push the boundaries of what cloud computing can deliver, building custom silicon for general-purpose and AI workloads and expanding EC2 into new form factors and deployment models that our customers in 2006 could not have imagined.

The 20 years in brief
In his 15th anniversary post, Jeff chose important milestones of EC2 that established the foundational building blocks that customers still rely on today. Amazon Elastic Block Store (2008) provided persistent block storage. Elastic Load Balancing, Auto Scaling, and Amazon CloudWatch (2009) made applications scalable and highly available. Amazon Virtual Private Cloud (2009) gave customers logically isolated networks. AWS Nitro System (2017) enabled faster innovation and enhanced security. AWS Graviton processors (2018) were designed for cost-sensitive scale-out workloads.

Over 20 years, EC2 grew from one to over 1,200 instance types to meet customer needs across general-purpose, compute-, memory-, and storage-optimized, accelerated computing, and high-performance computing families. These instances expanded from one AWS Region to 39 Regions globally. AWS also extended EC2 beyond the Region boundary with AWS Outposts (2018) running EC2 instances locally, AWS Local Zones (2019) place globally, and AWS Wavelength (2019) inside global 5G telecommunications carrier networks.

While I hate to play favorites, I want to choose some of my favorite EC2 launches of the past five years:

  • AWS Inferentia for ML inference at scale (2019): We introduced purpose-built ML inference instances (inf1) with AWS Inferentia chips. Amazon EC2 Inf2 instances became generally available in April 2023 for large-scale generative AI inference workloads. Together with the Inferentia family, AWS Trainium instances now give customers a full stack of AWS-designed silicon optimized for every phase of the AI lifecycle both inference and training.
  • EC2 Mac instances (2020): The first Mac instances (mac1) were built on Apple Mac mini with Intel Core i7 (Coffee Lake) on the AWS Nitro System. Mac M1 (mac2) instances launched in July 2022 as the first Arm-based macOS instances on EC2. M2 Pro Mac instances followed in 2023, M4 and M4 Pro Mac instances in 2025, M3 Ultra Mac instances and M4 Max Mac instances in 2026, giving Apple developers a complete range of cloud-based build and test environments for macOS, iOS, iPadOS, tvOS, watchOS, and visionOS apps.
  • AWS Trainium for full-stack AI workloads at scale (2021): In November 2021, we previewed Trn1 instances with AWS Trainium accelerators optimized for high-performance deep learning training. In December 2024, Trn2 instances powered by AWS Trainium2 launched, with Trn2 UltraServers linking 64 Trainium2 accelerators via NeuronLink for training trillion-parameter foundation models. At AWS re:Invent 2025, Trn3 UltraServers powered by AWS Trainium3 deliver the best token economics for next-generation agentic, reasoning, and video generation applications. A single Trn3 UltraServer interconnects up to 144 Trainium3 chips to train and serve the largest frontier models. Now, AWS Trainium3 delivers the leading price-performance for high-performance AI training and inference at scale.
  • EC2 Capacity Blocks for ML (2023): This new EC2 usage model further democratizes ML democratizes ML by making it easy to access GPU instances to train and deploy ML and generative AI models. You reserve the GPU capacity you need (initially P5 instances) for a future date and only for the duration you require. In November 2024, EC2 Capacity Blocks for ML added supported for provisioning in a matter of minutes and extending up to six months. Now, EC2 Capacity Blocks for ML supports P6-B300, P6-B200, P5e, P5en, P4d, P4de, Trn1, Trn2, and Trn3 instances in addition to P5.
  • AWS Graviton5 (2025): Building on eight years of Graviton innovation since 2018, we previewed Graviton5 chips in AWS re:Invent 2025 and launched M9g and M9gd instances powered by Graviton5 and built on the sixth-generation AWS Nitro System. C9g and C9gd followed in June 2026. Now, Graviton5 features 192 cores, a 5x larger cache, and up to 33% lower inter-core latency, making it well suited for the growing demands of agentic AI workloads such as real-time reasoning, code generation, and multi-step task orchestration that require continuous, high-throughput CPU compute at scale.
  • AWS Nitro Isolation Engine (2026): Customers wanted to see, not just hear from us, proof of workload isolation in the Nitro Hypervisor. The Nitro Isolation Engine is a purpose-built component inside the Nitro Hypervisor, harnessing formal verification to provide mathematical assurance that customer workloads are isolated from each other and AWS operators, pioneering a new standard for mathematically proven cloud security. This feature is also based on the sixth-generation AWS Nitro System which has continued to evolve since our introduction in 2017.

The foundation underneath it all
Despite two decades of innovation, the fundamental value proposition of Amazon EC2 has not changed. Customers use it to get secure, resizable compute capacity in minutes, pay only for what they consume, and scale on demand without long-term commitments. That same flexibility now extends to AI workloads at a scale no one anticipated in 2006.

EC2 remains the foundational compute layer of AWS. Amazon ECS, Amazon EKS, AWS Lambda, AWS Fargate, AWS Batch, Amazon EMR, Amazon SageMaker AI, and Amazon Bedrock ultimately run on EC2 capacity. Every architectural pattern customers have built over the past twenty years, from simple web servers to trillion-parameter foundation model training clusters, starts with a decision to launch an instance.

We made strong foundational decisions in 2006, and we left room for the service to grow. Twenty years later, that strategy of creating services that are minimal-yet-useful, launching quickly, and iterating rapidly in response to your feedback continues to guide how we build. The next twenty years of cloud computing will demand capabilities we have not yet imagined. Amazon EC2 will continue to be the foundation where your workloads run.

To learn more about Amazon EC2, visit the Amazon EC2 product page or check out what’s new with EC2.

— Channy

Amazon EC2 C9g and C9gd instances powered by AWS Graviton5 processors are now available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-ec2-c9g-and-c9gd-instances-powered-by-aws-graviton5-processors-are-now-available/

When you run compute-intensive workloads like real-time analytics, batch processing, video encoding, scientific modeling, or CPU-based machine learning inference, every percentage point of performance matters. You need instances that deliver higher throughput per vCPU, faster memory access, and more network bandwidth, all while keeping your costs in check.

Today I am happy to announce the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C9g and C9gd instances, powered by AWS Graviton5 processors. C9g instances are compute-optimized and deliver up to 25% higher performance per vCPU compared to previous-generation C8g instances. They feature the fastest memory of any processor instance in the cloud, with DDR5 8800MT/s DIMMs, 5x more L3 cache, and up to 3x higher packet-processing performance compared to Graviton4-based instances. The faster memory and larger caches mean your workloads spend less time waiting on data, translating into higher throughput for in-memory analytics, faster agentic loops, and more responsive real-time applications.

C9g instances are ideal for batch jobs, video encoding pipelines, or distributed analytics that can utilize Amazon Elastic Block Store (Amazon EBS) for storage. It is also a natural fit for agentic AI workloads, where concurrent environments and CPU-bound reasoning steps benefit from Graviton5’s higher core count and larger caches. As AI shifts from answering questions to taking actions, running code, and orchestrating multi-step tasks, the demand for CPU compute is growing, and C9g instances are built for this shift.

Some workloads also need fast local storage alongside that compute power. Choose C9gd when your application benefits from high-speed, low-latency local NVMe SSD storage, for example scratch space during HPC simulations, temporary caches for ML inference, or local buffers for ad-serving engines.

Graviton5-based instances with NVMe instance store volumes also support detailed performance statistics, providing high-resolution I/O metrics, including latency histograms broken down by I/O size, up to 1-second granularity and accessible via Amazon CloudWatch or nvme-cli at no additional cost.

C9g and C9gd instances at a glance
C9g and C9gd instances are available in 11 sizes ranging from medium to 48xlarge, plus a bare metal option. They offer up to 15% higher network bandwidth and 20% higher EBS bandwidth on average across sizes compared to the previous generation, with the largest 48xlarge size delivering up to 100 Gbps of network bandwidth and up to 72 Gbps of EBS bandwidth, a 2x increase.

C9g vCPUs Memory
(GiB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 Up to 15 Up to 12
large 2 4 Up to 15 Up to 12
xlarge 4 8 Up to 15 Up to 12
2xlarge 8 16 Up to 17 Up to 12
4xlarge 16 32 Up to 17 Up to 12
8xlarge 32 64 17 12
12xlarge 48 96 25 18
16xlarge 64 128 34 24
24xlarge 96 192 50 36
48xlarge 192 384 100 72
metal-48xl 192 384 100 72

C9gd instances add local NVMe SSD storage with up to 30% higher storage performance compared to previous-generation local storage instances.

C9gd vCPUs Memory
(GiB)
Instance Storage
(GB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 1 x 59 Up to 15 Up to 12
large 2 4 1 x 118 Up to 15 Up to 12
xlarge 4 8 1 x 237 Up to 15 Up to 12
2xlarge 8 16 1 x 474 Up to 17 Up to 12
4xlarge 16 32 1 x 950 Up to 17 Up to 12
8xlarge 32 64 1 x 1900 17 12
12xlarge 48 96 3 x 950 25 18
16xlarge 64 128 1 x 3800 34 24
24xlarge 96 192 3 x 1900 50 36
48xlarge 192 384 3 x 3800 100 72
metal-48xl 192 384 3 x 3800 100 72

Both families are well-suited for high-performance computing (HPC), batch processing, gaming, video encoding, scientific modeling, distributed analytics, CPU-based machine learning inference, and ad serving.

Here are some additional capabilities:

  • Instance Bandwidth Configuration (IBC) lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by up to 25%, helping you optimize performance for workloads with specific bandwidth requirements such as databases and caching.
  • ENA Express support for enhanced networking.
  • Up to 128 EBS volumes can be attached to virtual instances.
  • Support for Savings Plans, On-Demand, Spot Instances, Dedicated Instances, and Dedicated Hosts.

Nitro Isolation Engine
C9g and C9gd instances are the first compute optimized Amazon EC2 instances to feature the AWS Nitro Isolation Engine, a new capability of the AWS Nitro System. The Nitro Isolation Engine is a purpose-built component of the Nitro Hypervisor, implemented in Rust, that enforces isolation between virtual machines. It mediates all access to VM memory, CPU register state, and I/O devices through a minimal set of APIs.

To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see our technical white paper.

Now available
Amazon EC2 C9g and C9gd instances are now available in US East (Ohio, N. Virginia), US West (Oregon), and Europe (Frankfurt). Additional regions will follow.

You can launch C9g and C9gd instances today using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs. For pricing information, visit the Amazon EC2 Pricing page.

To learn more, visit the Amazon EC2 C9g and C9gd instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— seb

Why tombola chose Graviton-powered RG instances for Amazon Redshift

Post Syndicated from Prabhu Pandian original https://aws.amazon.com/blogs/big-data/why-tombola-chose-graviton-powered-rg-instances-for-amazon-redshift/

Part of Flutter Entertainment, the world’s largest online sports betting and iGaming operator, tombola is the world’s biggest online bingo community and has been using Amazon Redshift to run its data analytics workloads. Founded in Sunderland, UK, the company traces its roots to the 1950s, when it began printing bingo tickets during the golden age of the game. tombola launched online in 2006 and has since expanded to Italy, Spain, Denmark, and Sweden. The company builds all of its games in-house, holds the most prestigious Safer Gambling award, and recently partnered with Flutter sibling brand Sisal to bring its bingo application to Italian players.

In this post, you learn how tombola followed a strict engineering principle: no changes to production without evidence. That meant a head-to-head comparison of RA3 versus RG on their actual workload. You also see benchmark results on Amazon S3 Tables and the migration from RA3 to RG instances.

Current data architecture

Amazon Redshift sits at the center of tombola’s data architecture. The production cluster runs on RA3 nodes and serves multiple schemas with hundreds of tables, supporting every analytical workload the business runs, from sub-second application lookups to multi-minute extract, transform, load (ETL) transforms. What makes tombola’s Amazon Redshift workload distinctive is the breadth of what flows through it. Amazon Managed Workflows for Apache Airflow (Amazon MWAA) DAGs orchestrate pipelines across over 14 business domains, including segmentation, fraud detection, marketing, finance, and SafePlay responsible-gaming. Configuration-driven ingestion pipelines land data from SQL Server, Amazon DynamoDB, Amazon OpenSearch Service, Postgres, and external APIs into Bronze and Silver layers on Amazon Simple Storage Service (Amazon S3), before loading it into Amazon Redshift. From there, over 250 dbt models running on Amazon Elastic Container Service (Amazon ECS) transform the data into analytical gold layers. Outputs feed multiple downstream consumers: Amazon SageMaker for fraud scoring and churn prediction, Amazon DynamoDB for low-latency APIs, and region-specific pipelines spanning the UK, Italy, Spain, Denmark, and Sweden. As the application grew, with more domains, more DAGs, and more concurrent users, the team began evaluating ways to reduce steady-state query latency and lower compute cost without rearchitecting the system. When AWS made Graviton-powered RG nodes available for Amazon Redshift, the timing was right.

Benchmark performance results

The benchmark infrastructure was fully defined as infrastructure as code (IaC), making sure every test run was reproducible. The team deployed two test benchmark clusters (one RA3 and one RG) in a like-for-like configuration. They mirrored the settings (Amazon Virtual Private Cloud (Amazon VPC), security groups, AWS Key Management Service (AWS KMS), AWS Identity and Access Management (IAM) roles, and parameter groups) from the production environment to remove configuration drift. The benchmark runner was containerized as an Amazon ECS task (python:3.11-slim-bookworm ARM64 base), providing repeatable, isolated execution for each test round. Benchmark workloads were selected by analyzing production cluster logs and metrics, then classified into three tiers:

  • Heavy: ETL queries with multi-table CTE chains, full-table scans, and aggregation windows.
  • Medium: Business intelligence (BI) queries driving reporting and analytics dashboards.
  • Light: Application queries with sub-second response times.

Architecture

Scenarios tested

To validate the performance of Graviton-powered RG instances against the existing RA3 nodes, tombola designed four benchmark scenarios that progressively increase in complexity and realism. Together, these scenarios provide a comprehensive view of performance from isolated query execution through to sustained, real-world analytical workloads.

Scenario 01: Cold-cache, single-stream execution. This scenario isolates raw compute performance by running queries against a cold cache in a single stream, avoiding caching and concurrency as variables.

Per-query speedups ranged from 1.05× (light lookup queries) to 1.68× (heavy ETL transforms). Zero errors on both clusters (28 attempts each).

Weight Class RA3 p50 (ms) RG p50 (ms) Speedup
Heavy (ETL) 210,372 133,855 1.57×
Medium (BI) 2,193 1,642 1.34×
Light (App) 3.20 2.76 1.16×

The following chart shows per-query speedup ratios for the cold-cache scenario. Heavy ETL queries (left) show the largest gains, with speedups of 1.57–1.68×, and lighter queries still benefit at 1.05–1.16×. The pattern is consistent: RG’s advantage scales with query complexity.

Scenario 02: Warm-cache, single-stream execution. This scenario repeats Scenario 01 with the result cache enabled to confirm that RG maintains its latency advantage even when cached results are in play.

Per-query speedups ranged from 1.04× to 1.64×. Zero errors on both clusters (35 attempts each).

Weight Class RA3 p50 (ms) RG p50 (ms) Speedup
Heavy (ETL) 93,636 61,691 1.52×
Medium (BI) 2,189 1,584 1.38×
Light (App) 3.08 2.58 1.19×

With result caching enabled, the speedup pattern holds for non-cached queries. Cache hits on both clusters land in 118–185 ms, confirming the caching subsystem operates identically regardless of node type. The RG advantage appears exclusively on execution paths that bypass the cache.

Scenario 03: Concurrency sweep. This scenario introduces parallel load by sweeping through 1, 5, 10, and 20 concurrent streams, testing how each node type handles contention and queuing under pressure.

Both clusters used the same Concurrency Scaling configuration (max_concurrency_scaling_clusters=1, WLM-only). RG completed 482 more queries in the same wall-clock window.

Metric RA3 RG Improvement
Total queries completed 1,438 1,920 +33% throughput
Light p50 (ms) 3.44 3.04 1.13×
Medium p50 (ms) 20,784 15,055 1.38×
Errors 0 0 —

Under increasing parallel load (1, 5, 10, and 20 concurrent streams), RG maintained lower latencies and completed 33 percent more queries in the same wall-clock window. Both clusters used the same Concurrency Scaling configuration, so the throughput difference is attributable to per-node compute efficiency.

Scenario 04: Mixed realistic workload. This scenario combines the previous elements into a mixed realistic workload, running 10 streams simultaneously for 30 minutes with a weighted distribution of heavy, medium, and light queries to simulate actual production conditions.

This scenario best simulates production. The headline finding: heavy ETL queries saw speedups of up to 2.27× under concurrent load, and RG completed 46 percent more total queries in the same 30-minute window. Zero errors on both clusters.

Metric RA3 RG Improvement
Total queries completed 405 593 +46% throughput
Heavy p50 (ms) 1,186,572 642,294 1.85×
Medium p50 (ms) 2,319 1,631 1.42×
Light p50 (ms) 3.12 2.90 1.08×
Errors 0 0 —

The mixed-realistic scenario best simulates production. Under 10 concurrent streams over 30 minutes, heavy ETL queries showed speedups of up to 2.27×. RG’s per-vCPU throughput advantage compounds under contention, exactly the condition where production clusters spend most of their time.

Extended benchmark: Amazon S3 Tables (Iceberg) performance

tombola’s future data architecture will integrate with agents and revolves around Apache Iceberg, backed by Amazon S3 Tables. Amazon S3 Tables offer Amazon S3 storage that is specifically tuned for analytics, with built-in capabilities that keep making queries faster and helping lower storage costs for table data. They’re purpose-built to hold tabular datasets, such as daily purchase logs, streaming sensor readings, or ad impression events. In this model, data is organized into rows and columns, similar to how information is structured in a traditional database table. With that direction in mind, tombola also benchmarked Graviton’s performance querying Iceberg tables directly. The dataset includes player profiles, game session history, and geolocation data: a mix of wide tables and high-cardinality columns that stress both compute and I/O.

To evaluate performance across different scenarios, tombola generated queries at varying levels of complexity. Medium queries involve standard analytical functions like ranking and aggregation, and Medium-High queries introduce multi-step transformations with joins and cumulative calculations. At the High tier, queries combine distinct counting, conditional pivoting, and time-window aggregations. Very High queries are the most demanding: self-joins across the full dataset, multi-signal scoring logic, and advanced statistical functions. This tiered approach captures how each node type performs as computational demands increase.

As with the previous benchmarks, the team kept the test as comparable as possible: a true like-for-like evaluation between RG (powered by Graviton) and RA3 nodes of equivalent size.

Testing was split into two phases:

Phase 1: Concurrency. All queries were submitted simultaneously to measure how well each node type handles concurrent workloads. The goal was to understand throughput differences: how much more work RG nodes can push through under pressure compared to similarly sized RA3 nodes.

All queries were run simultaneously across multiple rounds:

Grouped bar chart showing total execution time across 3 rounds for RA3 vs Graviton

Phase 2: Sequential execution. Each query was run in isolation with full compute resources available. This removed concurrency as a variable and gave a clean read on raw query performance. The results were clear: RG outperformed RA3 across multiple query types, showing consistent gains when given dedicated compute.

In sequential execution, Graviton (RG) delivered consistent performance gains across all query complexity levels: Medium-complexity queries ran 45–73 percent faster (average 58 percent), Medium-High queries improved by 42 percent, High-complexity queries achieved 57–66 percent faster execution (average 62 percent), and Very High-complexity queries saw gains of 60–67 percent (average 63 percent). The results demonstrate that RG’s advantage scales with workload complexity, delivering the largest improvements on the most demanding analytical queries.

tombola’s modernization approach

tombola is modernizing its Amazon Redshift cluster using the Elastic Resize path to change from RA3 to RG node types. The operation snapshots the existing cluster, provisions a new RG cluster from that snapshot, and transfers data in the background. During this transfer period, the source cluster remains available in read-only mode. When the resize nears completion, Amazon Redshift automatically updates the endpoint to point to the new RG cluster and drops connections to the source. The team chose this approach because it aligns with their engineering principle of evidence-based changes: no production cutover without proof. The benchmark results, with zero errors across all scenarios against production-representative workloads, provided the confidence needed to proceed. After the resize is complete, the external tables, schemas, and query syntax remain unchanged. With RG’s integrated data lake query engine, tombola also removes its dependency on Amazon Redshift Spectrum. Data lake queries now run directly on cluster nodes within the Amazon VPC boundary, using existing IAM roles, with zero per-TB scanning charges.

Conclusion

The benchmark results make a compelling case for migrating tombola’s Amazon Redshift infrastructure from RA3 (Intel Xeon) to RG (Graviton4) instances. Across every scenario tested, RG delivered significant and consistent performance gains:

  • Cold-cache performance: 1.57× faster on heavy ETL queries, with per-query speedups up to 1.68×.
  • Warm-cache performance: 1.52× faster on heavy workloads, maintaining advantage even with result caching enabled.
  • Concurrency: 33 percent higher throughput under parallel load, with RG sustaining lower latencies as streams increased from 1 to 20.
  • Mixed realistic workload: 1.85× faster on heavy ETL queries and 46 percent more total queries completed, the scenario closest to production traffic patterns.
  • Amazon S3 Tables (Iceberg): Up to 51 percent faster under concurrent load and 57 percent faster in sequential execution, critical for tombola’s future lakehouse architecture.

Beyond raw performance, RG delivers architectural benefits that align with tombola’s strategic direction. The integrated data lake query engine removes Amazon Redshift Spectrum overhead and per-TB scan charges. The 4:3 node mapping (4 ra3.4xlarge nodes to 3 rg.4xlarge nodes) reduces infrastructure costs by 25 percent.

Based on these results, tombola are modernizing their production Amazon Redshift cluster to Graviton4-based RG instances. The work has already started and similar results as above are noticed.  The existing RA3 features, including concurrency scaling, data sharing, and system views, are fully supported on RG. This positions tombola to handle growing data volumes and user concurrency with better performance, greater cost efficiency, and a predictable pricing model as the application scales.

The results and benefits described in this post are specific to tombola’s workload and environment. Although Amazon Redshift RG instances powered by AWS Graviton4 processors can deliver significant performance improvements, actual results will vary based on factors including workload characteristics, data volumes, cluster configuration, and query complexity. We encourage you to evaluate RG instances with your own workloads to determine the benefits for your environment. To learn more, visit the Amazon Redshift marketing page and the Amazon Redshift documentation, or get started in the Amazon Redshift console.


About the authors

Prabhu Pandian

Prabhu Pandian

Prabhu has over 15 years of experience spanning data engineering, business intelligence, and data analytics. He has built a career on turning complex data challenges into actionable insights across industries including retail, healthcare, logistics, iGaming, and the public sector. He has led high-performing teams at organisations architecting data warehouses, building ETL pipelines processing tens of millions of records daily, and delivering analytics. Currently, as the Data Engineering Lead at tombola, he is focused on harnessing the power of AWS services to build scalable, optimised data platforms that drive real business value. He is passionate about engineering data infrastructure that is not just robust and efficient, but one that empowers teams to make faster, smarter decisions.

Akshay Srinivasan

Akshay Srinivasan

Akshay is a Data Engineer at tombola, where he runs the Data Platform & Reliability pod, shaping the architecture, scalability, and resilience of the company’s core data infrastructure across batch, streaming, and machine learning workloads. He favors open source tooling and composable AWS services, building platforms designed to be flexible and operationally sustainable. Over the past eight years he has built data platforms from the ground up across fintech, gaming, and enterprise environments, standing up greenfield infrastructure, automating complex operational workflows, and engineering systems in domains where data reliability directly affects regulatory and business outcomes. Having worked with Amazon Redshift since 2017, he has seen its evolution first-hand, from early node types through to the modern lakehouse capabilities the platform offers today.

Sidhanth Muralidhar

Sidhanth Muralidhar

Sidhanth is a Principal Technical Account Manager at AWS, where he partners with enterprise customers to design, scale, and optimize cloud-focused systems. He specializes in guiding organizations through complex architectural decisions across cost efficiency, reliability, performance, and operational excellence. His work increasingly sits at the intersection of data systems and AI as well, helping customers operationalize modern data architectures and build intelligent, production-ready systems.

Vlad Siniavin

Vlad Siniavin

Vlad is a Sr. Technical Account Manager at AWS with over 15 years of experience in building innovative solutions, products and services. He is driven by delivering measurable outcomes for his customers – whether that’s reducing operational risk, optimising costs, or accelerating cloud adoption. He believes the best technical guidance starts with deeply understanding what matters most to the customer and acting in their best interest.

AWS Weekly Roundup: AWS FinOps Agent in preview, Gemma 4 on Bedrock, Kiro Pro Max, and more (June 15, 2026)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-aws-finops-agent-in-preview-gemma-4-on-bedrock-kiro-pro-max-and-more-june-15-2026/

This week, New York City is hosting AWS Summit, bringing together builders, customers, and AWS teams for a full day of announcements, demos, and technical sessions at the Javits Center. I wrote blog posts for some of the Summit launches, so I am excited to see them go live this week. I just won’t be watching from the Javits Center. I’ll be at a four-day music festival, following the launches on my phone while trying to figure out how to put up a tent. If you weren’t able to attend in person like me, the keynote livestream is available on June 17, with Dr. Swami Sivasubramanian, VP of Agentic AI, and Chet Kapoor, VP of Security Services and Observability, covering new capabilities across developer tools, AI infrastructure, and security.

Here’s what happened this week.

Headlines
How frontier teams are reinventing AI-native development — Swami published a detailed post this week drawing on data from experiments across hundreds of Amazon engineering teams. The findings are worth reading carefully if you are thinking about how to structure AI adoption on your own team.

A six-engineer team rebuilt the Amazon Bedrock inference engine in 76 days, a project originally scoped for 30 developers over 12 to 18 months. The median productivity gain across structured pilots with Amazon Stores teams was 4.5x in normalized deployment velocity, with some teams exceeding 10x. Perfect Order Experience went from a two-week feature cycle to shipping in an afternoon. WW Grocery cut design document creation from five days to a few hours.

The post distills these results into five practices for becoming a frontier team. First, invest in agent context: build steering files, coding standards, and structured repositories before writing production code. Second, expect an initial slowdown while workflows are restructured, and push through it. Third, maintain a steady backlog of well-scoped tasks so agents can run in parallel without constant supervision. Fourth, make intent explicit through structured specifications before code generation begins. Fifth, shift testing left so agents can self-correct before code reaches the pipeline.

The post closes with a note that commit velocity is only part of the picture, and that a follow-up will cover release management, operations, security operations, and EOL upgrades.

AWS FinOps Agent is now available in preview — AWS FinOps Agent is a new agent for FinOps practitioners and engineering teams that answers cost questions, surfaces optimization opportunities, investigates cost anomalies, and runs recurring FinOps workflows on a defined schedule. You can use it to query your AWS costs, generate cost reports for finance and engineering teams, and surface rightsizing, idle resource, and Savings Plans recommendations from AWS Cost Optimization Hub and AWS Compute Optimizer. The agent can open Jira tickets on your behalf based on those recommendations. When a cost anomaly is detected, FinOps Agent can automatically investigate the root cause and post findings to a Slack channel.

Last week’s launches
I’ll start with one I wrote this week, then cover the other launches that caught my attention:

  • Amazon EC2 M9g and M9gd instances are now generally available — Powered by AWS Graviton5 processors and built on the sixth-generation AWS Nitro System, M9g instances deliver up to 25% better compute performance compared to Graviton4-based instances, with up to 35% faster performance for web applications, up to 35% for machine learning inference, and up to 30% for databases. Graviton5 is the first processor in the AWS fleet to support PCIe Gen6 and DDR5-8800 memory, and includes a 5x larger L3 cache compared to the previous generation. M9g and M9gd instances offer up to 15% higher network bandwidth and 20% higher Amazon EBS bandwidth on average across sizes compared to M8g. This release also introduces the Nitro Isolation Engine, an enhancement to the Nitro System that uses formal verification to provide mathematically proven isolation between virtual machines — establishing Nitro as the first formally verified cloud hypervisor. M9gd instances add up to 11.4 TB of NVMe SSD local storage with 30% higher IOPS compared to M8gd. Both instance types support Instance Bandwidth Configuration (IBC) for adjusting bandwidth allocation between EBS and VPC networking by up to 25%.
  • Anthropic Claude Fable 5 on Amazon Bedrock — Claude Fable 5 launched on Amazon Bedrock on June 9, bringing extended asynchronous task execution, advanced vision capabilities across diagrams, charts, and PDFs, and proactive self-verification. Access requires opting into data sharing via the Data Retention API before invoking the model; Anthropic requires 30-day retention of inputs and outputs for Mythos-class models. Important note on availability: On June 12, Anthropic asked AWS to revoke access to Claude Fable 5 and Claude Mythos 5 for all users to support compliance with a US Government export control directive. All other models, including Opus 4.8, are unaffected. Read the Anthropic statement for details. AWS will share further updates as they become available.
  • Gemma 4 models are now available on Amazon Bedrock — The Gemma 4 family from Google DeepMind is now available on Amazon Bedrock across three variants: Gemma 4 31B (dense, 256K-token context window, suited for reasoning and coding workloads), Gemma 4 26B-A4B (mixture-of-experts architecture, targeting cost- and latency-sensitive workloads), and Gemma 4 E2B (smallest variant, designed for low-latency interactive use cases). All three support native function calling, structured output, reasoning, response streaming, multimodal input across text, image, video, and audio, and more than 35 languages.
  • Amazon OpenSearch Service launches MCP Apps for agentic observability — Amazon OpenSearch Service now supports MCP Apps, enabling observability workflows inside compatible agentic IDEs including Claude Desktop and VS Code. An AI agent in your local environment can investigate incidents using logs, traces, metrics, and alerts stored in OpenSearch domains, collections, and Amazon Managed Service for Prometheus. Each MCP App tool call returns a dual response: a text summary for the agent to reason over and an interactive visualization rendered in the same conversation thread. Available MCP App tools cover log, metrics, and trace investigation; service performance; topology; dynamic visualizations; agent health; cluster health; and instrumentation scoring.

Other AWS news
Here are some additional posts and updates you may find useful:

  • AWS CLI v1 enters maintenance mode — When CLI v1 enters maintenance mode, the botocore and s3transfer dependencies will be vendored directly into the CLI v1 codebase rather than installed as separate packages. This means upgrading CLI v1 will no longer update the standalone botocore or s3transfer packages, and installing those packages independently will have no effect on the versions used by CLI v1. Environments with both CLI v1 and boto3 installed will contain separate copies of these libraries. New CLI v1 releases will be limited to critical bug fixes and security issues. The recommended path is to migrate to AWS CLI v2.
  • AWS Workload Credentials Provider is now available — AWS has launched a new Workload Credentials Provider that enables workloads to obtain short-term AWS credentials without requiring long-term access keys. This supports credential management for applications running outside of AWS, giving teams a way to follow least-privilege access patterns for workloads in third-party or on-premises environments.
  • Kiro Pro Max is now available — Kiro has introduced a new Pro Max tier, adding higher usage limits, access to the latest frontier models, and additional agentic capabilities for development teams. Kiro Pro Max is designed for professional developers who need sustained, high-volume use across coding, specification generation, and agent-driven tasks.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

Visit the AWS Builder Center to meet other builders, contribute solutions, and find resources that help you keep building. You can also browse upcoming AWS-led in-person and virtual events, plus developer-focused sessions.

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Now available: Amazon EC2 M9g and M9gd instances powered by new AWS Graviton5 processors

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/now-available-amazon-ec2-m9g-and-m9gd-instances-powered-by-new-aws-graviton5-processors/

AWS Graviton processors have improved steadily across generations, with each iteration delivering advances in compute performance, price-performance, and energy efficiency. At re:Invent 2025, we announced Amazon EC2 M9g, the first Graviton5-powered instances, in preview. Since then, customers have tested M9g across a wide range of workloads and shared their results. ClickHouse saw a 36% performance boost compared to M8g, with zero code changes. Honeycomb achieved 36% better throughput per core compared to Graviton4, across a 6-month A/B test of production observability workloads. HubSpot deployed M9g for MySQL databases and saw query duration drop by up to 60%. Today, M9g instances are generally available, alongside the new M9gd instances for customers who need high-speed, low-latency local NVMe SSD storage. Both are powered by Graviton5, the most powerful and most energy efficient processor AWS has ever built.

While many Arm-based instances have been introduced across the industry, no one comes close to the breadth and depth of the AWS Graviton footprint. After five generations of custom silicon and eight years of continuous investment, Graviton powers over 350 instance types serving more than 120,000 customers, from startups to large enterprises, a robust ISV partner ecosystem, and a broad set of managed services. You can use Graviton for a broad variety of workloads, including web applications, microservices, analytics, databases, machine learning (ML) inference, electronic design automation (EDA), gaming, and video encoding. As workloads grow more compute-intensive and data-driven, many have asked for more processing power, along with greater network and storage bandwidth to move more data and complete workloads faster. We’ve also designed these instances to efficiently package compute, memory, and I/O to maximize energy utilization.

As AI shifts from answering questions to taking actions, running code, using tools, evaluating results, and orchestrating multi-step tasks, the demand for CPU compute is growing rapidly. Graviton5 is built for this shift. With 192 cores, a 5x larger L3 cache, up to 33% lower inter-core latency, and DDR5 memory delivering high bandwidth, Graviton5 helps agents spend less time waiting on CPU-bound steps, processing more instructions, handling large numbers of concurrent environments, and keeping accelerators moving.

Meta is deploying Graviton at scale starting with tens of millions of cores to support its agentic AI efforts, making Meta one of the largest Graviton customers in the world. Agentic AI workloads, including real-time reasoning, code generation, and the orchestration of multi-step tasks, are CPU-intensive and benefit from the higher compute performance, larger caches, higher memory bandwidth, and core density in Graviton5.

What’s new in M9g and M9gd
Built on the sixth-generation AWS Nitro System, M9g instances are powered by AWS Graviton5 processors that deliver higher compute performance, larger caches, and improved memory and I/O scalability compared to Graviton4 processors. Graviton5 offers up to 25% better compute performance compared to Graviton4-based instances, with up to 35% faster performance for web applications, up to 35% for machine learning inference, and up to 30% for databases. As the first CPU in the AWS fleet to support the latest generation of PCIe Gen6 and DDR5-8800 memory, AWS Graviton5 instances deliver the fastest memory of any processor instances in the cloud, and 5 times more L3 cache compared to the previous generation. These improvements also come with better energy efficiency, helping you meet sustainability targets without compromising capability.

Networking and storage bandwidth have been expanded to keep pace with compute growth. M9g and M9gd instances offer up to 15% higher network bandwidth and 20% higher Amazon Elastic Block Store (Amazon EBS) bandwidth on average across sizes, with up to twice the network bandwidth for the largest instance size. M9g and M9gd instances also support Instance Bandwidth Configuration (IBC), a feature that helps you adjust the allocation of bandwidth between Amazon EBS and Amazon Virtual Private Cloud (Amazon VPC) networking for an Amazon EC2 instance by up to 25%. IBC can help optimize performance for workloads with specific bandwidth requirements, such as database read and write performance, query processing, and logging. These enhancements support faster data movement and improved throughput for workloads that rely on high I/O performance.

Security and isolation are foundational requirements for running workloads in the cloud. Within the Nitro System, the AWS Nitro Hypervisor is designed to isolate instances from each other as well as AWS operators. With M9g and M9gd instances we are raising the bar on security even further with the introduction of Nitro Isolation Engine. Nitro Isolation Engine is an enhancement to the Nitro System, which enforces isolation of instances and harnesses formal verification to provide assurances of isolation with mathematical precision. Nitro Isolation Engine is a purpose-built component that is responsible for enforcing isolation between virtual machines, including mediation of all access to virtual machine memory, CPU register state, and I/O devices through a minimal set of APIs. Nitro Isolation Engine leverages formal verification, a technique to mathematically demonstrate that the hardware or software behaves as intended, and not just in specific test cases. This intensive verification technique establishes Nitro as the first formally verified cloud hypervisor, pioneering a new standard for mathematically proven cloud security.

M9g instances provide one vCPU for every four GiB of memory and are well suited for a broad range of general-purpose workloads, including application servers, microservices, midsize data stores, gaming servers, caching fleets, containerized applications, large-scale Java applications, code repositories, web applications, and agentic AI.

For workloads that need high-speed, low-latency local storage, M9gd instances provide up to 11.4 TB of NVMe SSD storage and 30% higher IOPS and storage performance compared to Graviton4-based M8gd instances. M9gd instances are well suited for general-purpose workloads that require a balance of compute and memory with high-speed, low-latency local storage, including application servers, microservices, gaming servers, midsize key-value data stores, caching fleets, data logging, media processing, batch and log processing, and applications that need temporary storage such as caches and scratch files.

Here are the key specifications across the family:

M9g vCPUs Memory (GiB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
medium 1 4 Up to 15 Up to 12
large 2 8 Up to 15 Up to 12
xlarge 4 16 Up to 15 Up to 12
2xlarge 8 32 Up to 17 Up to 12
4xlarge 16 64 Up to 17 Up to 12
8xlarge 32 128 17 12
12xlarge 48 192 25 18
16xlarge 64 256 34 24
24xlarge 96 384 50 36
48xlarge 192 768 100 72
metal-48xl 192 768 100 72

M9gd instances include local NVMe SSD storage. The table below shows the instance storage for each size. Compute, memory, network, and EBS bandwidth specifications are the same as M9g.

M9gd vCPUs Memory (GiB) Instance storage (GB) Network bandwidth (Gbps) EBS bandwidth (Gbps)
medium 1 4 1 x 59 NVMe SSD Up to 15 Up to 12
large 2 8 1 x 118 NVMe SSD Up to 15 Up to 12
xlarge 4 16 1 x 237 NVMe SSD Up to 15 Up to 12
2xlarge 8 32 1 x 475 NVMe SSD Up to 17 Up to 12
4xlarge 16 64 1 x 950 NVMe SSD Up to 17 Up to 12
8xlarge 32 128 1 x 1900 NVMe SSD 17 12
12xlarge 48 192 3 x 950 NVMe SSD 25 18
16xlarge 64 256 1 x 3800 NVMe SSD 34 24
24xlarge 96 384 3 x 1900 NVMe SSD 50 36
48xlarge 192 768 3 x 3800 NVMe SSD 100 72
metal-48xl 192 768 3 x 3800 NVMe SSD 100 72

Now available
M9g and M9gd instances are available in the US East (N. Virginia), US East (Ohio), US West (Oregon), and Europe (Frankfurt) Regions. M9g and M9gd instances are available for purchase through Savings Plans, On-Demand, Spot Instances, Dedicated Instances, or Dedicated Hosts. For more information, visit Amazon EC2 pricing.

To get started with M9g and M9gd instances, several resources are available. The AWS Graviton Getting Started Guide is a technical guide covering how to build, run, and optimize workloads on Graviton-based instances. The Graviton Savings Dashboard helps you track and measure the cost savings from running workloads on Graviton-based instances. And AWS Transform is an AI-powered service that automates code transformations for migrating Java applications from x86 to Graviton-based Amazon EC2 instances, handling compatibility analysis, automated recompilation, dependency updates, and validation.

To learn more about Graviton-based instances, visit AWS Graviton Processors or Level up your compute with AWS Graviton.

— Esra

Migrating your Java applications to AWS Graviton using AWS Transform custom

Post Syndicated from Hahnara Hyun original https://aws.amazon.com/blogs/compute/migrating-your-java-applications-to-aws-graviton-using-aws-transform-custom/

For Java applications, modern JVMs like Amazon Corretto and OpenJDK are highly optimized for Arm64 and modern applications that are pure Java often require zero changes to run on Graviton. In many cases, applications aren’t fully modernized or purely Java and have a range of dependencies. When you’re responsible for migrating workloads, it’s helpful to use a systematic approach that surfaces issues, proposes solutions, and does the transformation work for you at scale.

That’s why we built the Java x86 to Graviton Migration transformation for AWS Transform custom (ATX). This is an AI-powered agent that analyzes your Java codebase, creates a migration plan, and executes the transformation—complete with version-controlled commits at every step. With ATX you can efficiently assess hundreds of Java applications simultaneously and quickly learn which applications require no changes and which ones need modifications. This streamlines the process of estimating the scope of effort, while also having suggested code updates before you even start.

ATX is available as a Kiro power, a VS Code extension, and an Agent Skill if you’d like to use it directly within other AI assistants to reduce context switching. While we will be using ATX to highlight how you can rapidly accelerate a Graviton migration, we have also published an open source Graviton universal skill based on the Agent Skills open standard so that you have the flexibility to use the skill natively within Kiro, Claude Code, Codex, or the platform of your choice.

AWS Graviton processors, based on the Arm64 architecture, can provide up to 40% better price performance over comparable x86-based instances for a wide variety of workloads. Now customers can use AI tools to quickly migrate workloads to Graviton.

The Java x86 to Graviton migration transformation

At a high level, we recommend customers finish any major version Java updates prior to migrating to Graviton and there’s a separate Java Version Upgrade transformation available for this use case. The Java x86 to Graviton Migration transformation requires a minimum of Java 8 and won’t incorporate Java version updates into the code changes.

The Java x86 to Graviton Migration completes multiple steps with work divided across multiple AI agents within the AWS Transform service, covering things like:

  • Native library analysis – Identifies Java Native Interface (JNI) dependencies and finds Arm64-compatible alternatives
  • Dependency updates – Updates libraries to versions with Arm64 support
  • Build configuration – Modifies Maven/Gradle configs for multi-architecture builds
  • Architecture-specific code – Refactors hard-coded x86 assumptions
  • Unit Test – Verifies compatibility at runtime given unit tests are in the project
  • Documentation – Creates migration notes and runbooks for your team

The agent automatically detects your Java version, manages runtime switching as needed during analysis, and handles much of the environment complexity for you such as multi-module project detection or Maven or Gradle auto-detection. Transformation completion times vary, but for many applications you can expect it to take roughly an hour (ATX works well with repos under 300K lines of code).

In this post, we:

  • Walk through the requirements for running the Java x86 to Graviton Migration transformation.
  • Help you familiarize yourself with ATX using a single Java application with Interactive Mode
  • Outline how to assess Graviton compatibility across the Java applications that you want to migrate to Graviton in a single batch and summarize the results with Campaign Mode.

By the end, you should have a good idea of how Java x86 to Graviton Migration transformation functions and have a summary of the expected code changes and dependency updates needed for each of your Java applications, along with version-controlled code updates.

Graviton transformation requirement

The Java x86 to Graviton migration transformation should run on an Arm64 machine.

The agent doesn’t just read your code, it builds, loads native libraries, and validates your application’s runtime behavior on Arm64. If you run the transformation on an x86 machine, the agent can identify compatibility issues but can’t execute build validation or run tests.

If you try to run on x86, you will see the following error message:

⚠  This transformation requires Arm64 architecture.    
Detected: x86_64        
Please run ATX on an Arm64 environment. See documentation for options.

To get started you need a Graviton instance or Apple Mac laptop running Arm64 with the ATX CLI, build tools, and Java JDKs that your project requires. The project source code should also be loaded locally onto the machine running the ATX CLI. Because Apple silicon is Arm64-based, it’s possible to build, load, and verify Arm64 based dependencies for a quick proof-of-concept. However, we recommend running the transformation in an environment that reflects what you plan to deploy in production to surface any potential OS level incompatibilities.

Requirements

Requirement Details
AWS Transform custom permissions AWS Identity and Access Management (IAM) policies for the Transform service (see Authentication docs)
Arm64 execution environment Amazon Elastic Compute Cloud (Amazon EC2) Graviton instance or Apple Silicon Mac. Running on x86 limits validation to static analysis only. Phase 3 (build/test) requires Arm64.
Node.js 20+ Required by the AWS Transform CLI. Use the official installer at nodejs.org/en/download. Package managers (dnf, yum) can install an older version.
Git AWS Transform custom uses local Git for version control during the transformation.
AWS Transform CLI Installed using the setup script (see Client Setup for the curl command).
Java build tooling A JDK (Arm64 build, e.g. Amazon Corretto or OpenJDK), Maven and/or Gradle as required by the target project. These are not optional for Java transformations. The agent needs them for dependency analysis, native library scanning, and build validation.

Running the Graviton transformation with Interactive Mode

With your code on an Arm64 environment and all the prerequisites for the transformation, we can begin the transformation.

Step 1: Navigate to Your Project and create or clone a git repo

cd /home/developer/workspace # Docker 
# or 
cd ~/workspace # AMI
git init

We recommend not pointing to the main branch of the repository of your application. You can work in a local git environment or create a separate branch. ATX needs the ability to commit changes as it iteratively transforms your code. The final decision on which commits are pushed is up to the developer.

Step 2: Launch ATX Interactive Mode

Enter the following command to launch ATX interactive mode.

atx

ATX starts in interactive mode:


To view available transformations, in a separate terminal enter:

atx custom def list > custom_list.txt

The AWS Managed transformations will be listed first, followed by User-created transformations that you’ve developed.

Step 3: Select the Graviton transformation

Enter the following into atx cli:

>AWS/early-access-java-x86-to-graviton

ATX will prompt you for next steps and your project details:

> Would you like to:+ c to abort or provide feedback)
1. View the entire transformation definition
2. View specific sections of the transformation definition
3. Apply this transformation to your code
4. Modify this transformation
> 3
> What is the file system path to the code repository where you want to apply this transformation?
> .

Note that because this is an AWS Managed Transformation, you can’t view the complete transformation definition or modify it. However, you can provide additional context customized to your use case. Keep in mind that the Transformation won’t make permanent changes to your code through the transformation process.

Step 4: Provide additional context

ATX might ask clarifying questions to tailor the transformation:

Step 5: Review the analysis

ATX analyzes your codebase:

Analyzing your codebase...[████████████████████████████████████████] 100%
✓ Parsed 847 Java files
✓ Analyzed 234 dependencies  
✓ Identified 12 native library usages
✓ Scanned build configuration
✓ Evaluated test coverage
Analysis complete. Preparing migration plan...

Step 6: Review the migration plan

ATX presents a detailed plan before making changes:

═══════════════════════════════════════════════════════════════
                    MIGRATION PLAN
═══════════════════════════════════════════════════════════════

I've analyzed your project and here's what I'll do:

PHASE 1: Dependency Updates (12 changes)
────────────────────────────────────────
 • Update netty-transport-native-epoll 4.1.85 → 4.1.100
   Reason: Arm64 support added in 4.1.94
   
 • Update snappy-java 1.1.8.4 → 1.1.10.5  
   Reason: Current version lacks Arm64 native binaries
   
 • Update lz4-java 1.7.1 → 1.8.0
   Reason: Arm64 optimization improvements
   
 • ... (9 more dependency updates)

PHASE 2: Build Configuration (3 changes)
────────────────────────────────────────
 • Add Arm64 classifier to native dependency declarations
 • Configure multi-architecture Docker build
 • Add Graviton-optimized JVM flags to startup scripts

PHASE 3: Code Modifications (2 changes)
────────────────────────────────────────
 • Refactor ProcessorArchitecture.java
   Current: Hard-coded x86_64 assumption
   Change: Add Arm64 detection logic
   
 • Update NativeLibraryLoader.java
   Current: Loads x86-specific .so files
   Change: Architecture-aware library loading

PHASE 4: Testing & Validation
────────────────────────────────────────
 • Run build and tests on Arm64
 • Generate migration report and documentation

═══════════════════════════════════════════════════════════════

? How would you like to proceed?
  ❯ Execute the full plan
    Execute phase by phase (review each)
    Modify the plan
    Ask questions about the plan
    Export plan and exit

Step 7: Ask questions, request changes

This is your chance to understand and adjust:

? Ask questions about the plan:

You: Why are you updating netty to 4.1.100? 

ATX: Good concern. Netty 4.1.94 was the first version with Arm64 
     native transport support, which is required for optimal 
     performance on Graviton. 
     
     However, I can adjust this:
     
     Option 1: Use 4.1.94 (minimum Arm64 support)
     Option 2: Use 4.1.97 (includes Arm64 bug fixes)
     Option 3: Keep 4.1.100 (latest stable with Arm64)
     
     Which would you prefer?

You: Let's go with 4.1.100.

Step 8: Execute the Transformation

When you’re ready:

? How would you like to proceed?
  ❯ Execute the full plan

Starting transformation...

Phase 1: Dependency Updates
───────────────────────────
[1/12] Updating netty-transport-native-epoll...
       ✓ Modified pom.xml
       ✓ Committed: "chore(deps): update netty to 4.1.97 for Arm64 support"

[2/12] Updating snappy-java...
       ✓ Modified pom.xml  
       ✓ Committed: "chore(deps): update snappy-java to 1.1.10.5 for Arm64"

... (progress continues)

Phase 2: Build Configuration
───────────────────────────
[1/3] Adding Arm64 classifiers...
      ✓ Modified pom.xml
      ✓ Committed: "build: add Arm64 native classifiers"

... (progress continues)

Phase 3: Code Modifications
───────────────────────────
[1/2] Refactoring ProcessorArchitecture.java...
      ✓ Modified src/main/java/com/example/util/ProcessorArchitecture.java
      ✓ Committed: "feat: add Arm64 architecture detection"

... (progress continues)

Phase 4: Validation
───────────────────
Running build... ✓
Running tests... ✓ (847 passed, 0 failed)

═══════════════════════════════════════════════════════════════
                 TRANSFORMATION COMPLETE
═══════════════════════════════════════════════════════════════

Summary:
 • 17 files modified
 • 3 files created  
 • 14 commits made
 • All tests passing

Generated Artifacts:
 • GRAVITON_MIGRATION_REPORT.html  - Full migration report
 • MIGRATION_RUNBOOK.md            - Deployment guide for your team
 • commit-log.txt                  - All commits with descriptions

Your code is now Graviton-ready!

After the transformation is complete, you can now performance test and load test on Graviton instances to configure your scaling policies or target thresholds to maximize price/performance on Graviton. For more guidance on performance testing, see the AWS Graviton Technical Guide.

What you get after transformation

Version-controlled history

Every logical change is a separate commit:

$ git log --oneline -10

a3f2b1c (HEAD) docs: add Graviton migration runbook
b82d4e5 test: add Arm64 architecture verification tests
c9a1f3d feat: add Arm64 architecture detection
d4e7c2a build: configure multi-arch Docker build
e5f8d1b build: add Arm64 native classifiers
f6a9e2c chore(deps): update lz4-java to 1.8.0
g7b0f3d chore(deps): update snappy-java to 1.1.10.5
h8c1a4e chore(deps): update netty to 4.1.97 for Arm64 support
...

Each commit is atomic and revertible. If something doesn’t work, you can git revert specific changes.

Migration report

A comprehensive markdown report covering:

  • What was changed and why
  • Dependencies that were updated
  • Code modifications with before and after diffs
  • Performance optimization recommendations

Migration runbook

A deployment guide for your team:

  • Pre-deployment checklist
  • JVM flags designed for Graviton
  • Monitoring and rollback procedures

Additional resources on migrating to Graviton on an infrastructure level can be found in the Transition Guide.

Assessing Graviton compatibility for multiple Java applications with Campaign Mode

When you’re ready to start migrating multiple applications, you might want to opt for an automated process that removes the manual effort of going back and forth with the transformation agent after each transformation step with campaign mode. The following command allows ATX CLI to go through a full transformation that you can check back in with after it’s completed. This limits the additional customization and context that you might want to provide the agent.

As mentioned in the first step of running a Graviton Transformation, the environment that the code is transformed in and decision of which commits are pulled into the main repo is up to the developer. Running in campaign mode across several applications doesn’t require accepting and pushing code changes. Therefore, this automated method is most useful when you want to gauge a high-level overview of effort required to migrate across several or even hundreds of applications.

atx custom def exec \
--code-repository-path /path/to/myapp \
--non-interactive \
--trust-all-tools \
--campaign  \
--repo-name myapp \
--add-repo

This command can be added into scripts, allowing further automations to be built into continuous integration and delivery (CI/CD) pipelines or scaling transformation jobs across several repos without manually entering prompts as previously shown through interactive mode.

The status of transformations running with campaign mode will be displayed in the AWS Transform Web UI. Setting up the Web UI is a prerequisite to running a transformation in campaign mode.

In addition to this view, if you run the transformation across multiple applications, you can generate a consolidated dashboard with an agent of your choice. Gather the transformation results into a centralized directory, then use the following prompt for example:

Analyze all Java application Graviton transformation summaries in <directory>/<path>/ and create a comprehensive dashboard that includes: 
 
1. Executive summary with key metrics (total apps, compatibility rate, code changes required) 
2. Application summary table with columns: Application name, Type, Java version, Dependencies count, Code changes, Compatibility %, Status 
3. Code changes analysis - which apps needed changes and why 
4. Dependency transformation analysis - common dependencies and their ARM64 status, any upgrades required 
5. Native library analysis - which apps use native libs and their compatibility 
6. Performance expectations - JWT/crypto improvements, general performance gains, cost-performance ratios 
7. JVM optimization patterns - common flags used across applications 
8. Build system patterns - Maven/Gradle usage, Docker multi-arch support 
9. Test results summary - pass/fail rates, pre-existing vs ARM64 issues 
10. Common libraries requiring changes (or note if none) 
11. Deployment readiness assessment 
12. Risk assessment with mitigation strategies 
13. Migration recommendations with phased approach 
14. Documentation summary - total docs created and their coverage 
 
Read graviton-validation/00-summary.md from each application subdirectory. Consolidate findings into a single comprehensive markdown dashboard with tables, metrics, and actionable insights. 
 
Focus on: compatibility rates, code change requirements, dependency issues, performance expectations, and migration readiness. 

Keep in mind that agents might output outcomes of the migration that aren’t sourced from the transformation summaries. As a result, we recommend that you use the summary as a high-level estimate of the technical effort required for migrating to Graviton.

Conclusion

The AWS Transform custom Java x86 to Graviton Migration transformation alleviates the guesswork in Graviton migrations by using AI for dependency analysis, compatibility assessment, code refactoring, and runtime validation. Development teams can evaluate hundreds of Java applications simultaneously, with each transformation providing atomic version-controlled commits for straightforward rollback and clear change tracking. The tool offers two modes: 1) interactive mode for hands-on, application-by-application migration with developer review at each step, or 2) campaign mode for automated assessment across multiple applications. ATX converts unknown Graviton migration effort into defined requirements through automated compilation and runtime testing. This provides a more efficient way to evaluate workload compatibility and migrate to Graviton.

The Java x86 to Graviton Migration transformation is one of a range of pre-built AWS Managed Transformations but you can also create custom transformations unique to your own use case that can be scaled to drive migrations across your organization. Learn more on the AWS Transform custom website or documentation.

Resources

Meet Amazon Redshift RG – AWS Graviton-based instances with an integrated data lake query engine delivering up to 2.4x better performance at 30% lower price than RA3

Post Syndicated from Ankit Sahu original https://aws.amazon.com/blogs/big-data/meet-amazon-redshift-rg-aws-graviton-based-instances-with-an-integrated-data-lake-query-engine-delivering-up-to-2-4x-better-performance-at-30-lower-price-than-ra3/

On May 12, 2026, we announced the general availability of Amazon Redshift RG instances, powered by AWS Graviton processors. RG instances are up to 2.2x as fast for data warehouse workloads and up to 2.4x as fast for data lake workloads, all at 30% lower price per vCPU compared to RA3 instances. RG instances support all data lake formats supported by RA3 and eliminate Amazon Redshift Spectrum’s per-TB scanning charges. RG instances feature a custom-built integrated vectorized query engine, making them a more performant and cost-effective foundation for unified analytics.

We are launching with two instance sizes: rg.xlarge and rg.4xlarge, with additional sizes coming later this year.

Why we built this

RG instances bring the power of AWS Graviton processors to Amazon Redshift Provisioned clusters for the first time, paired with a purpose-built vectorized query engine. By combining Graviton’s superior price-performance with the latest Amazon Redshift innovations, RG instances deliver a step-change improvement across two dimensions: significantly lower cost and meaningfully faster performance for both warehouse and data lake workloads using Apache Iceberg and Apache Parquet. We built RG to help you avoid choosing between performance and economics. Graviton costs less to operate, and we’re passing that benefit to you while simultaneously raising the performance bar. Equally important, we designed RG to maintain full feature parity with RA3, so you can modernize your existing clusters without rearchitecting workloads or sacrificing capabilities you depend on today.

This combination is also increasingly critical for agentic artificial intelligence (AI) workloads. AI agents operating at scale generate a new class of analytics demand: high volumes of unique, unpredictable queries that require fast, low-latency responses to keep agents productive. Traditional price-performance ratios make running these workloads at scale cost-prohibitive. RG instances address this head-on. Lower per-vCPU pricing makes sustained high-query volumes economically viable, while improved query performance makes sure agents get answers fast enough to remain effective. Together, this provides the foundation for AI-driven analytics at the scale and economics that agentic workloads demand.

What’s new

RG instances: Better performance, lower cost

RG instances run on AWS Graviton, Amazon’s custom-designed cloud processor built from the ground up to deliver superior price-performance and energy efficiency. This translates directly into RG instances offering more compute cores, higher memory bandwidth, and lower inter-process communication latency compared to RA3, with performance improvements across warehouse, data lake, and mixed workloads.

Graviton costs less to operate, and we’re passing that benefit directly to you. RG instances are priced at a 30% lower cost per vCPU compared to RA3. Reserved Instance pricing follows the same model, making RG Reserved Instances equally 30% less costly than RA3. For pricing details, visit the Amazon Redshift pricing page.

Performance results

RG instances deliver faster, more efficient analytics across your most demanding warehouse and data lake workloads, whether you’re querying structured data in Amazon Redshift Managed Storage (RMS), running analytics over Iceberg tables in Amazon Simple Storage Service (Amazon S3), or processing Parquet files at scale. Iceberg workloads see the most significant gains, delivering up to 2.4x faster query execution. Parquet workloads deliver up to 1.5x faster query execution, and RMS-based data warehouse workloads deliver up to 2.2x faster query execution. All performance improvements are measured using industry-standard TPC-DS and TPC-H benchmarks at 10 TB scale on rg.4xlarge instances.

When combined with RG’s 30% lower per-vCPU pricing compared to RA3, these performance gains translate to even greater price-performance improvements, delivering more analytics value for every dollar spent.

Built-in data lake query engine – no more Spectrum charges

With RA3, data lake queries were offloaded to a separate fleet of nodes called Amazon Redshift Spectrum, scanning data externally and returning results back to the cluster. This architecture introduced network overhead, added latency, and imposed a $5/TB scanning charge on every query. RG instances change this fundamentally with a custom-built vectorized data lake engine running directly inside the cluster, eliminating Spectrum scanning charges.

The purpose-built vectorized engine includes a highly optimized scan layer that implements the latest data pruning techniques, a purpose-built I/O subsystem, and a range of optimizations that use Graviton’s processing capabilities to make scanning Iceberg and Parquet data highly efficient. Beyond raw scan performance, the engine introduces JIT ANALYZE, a capability that automatically collects and uses statistics for data lake tables during query execution. This eliminates the need for manual statistics collection. The system uses intelligent heuristics to identify queries that will benefit from statistics, maintains lightweight sketch data structures, and builds high-quality table-level and column-level statistics, all transparently. Having up-to-date statistics on data lake tables can deliver orders-of-magnitude improvements in query performance, and with JIT ANALYZE, you get this benefit automatically without operational overhead.

What customers are saying

Sean Lynch, Vice President, Data and Architecture, Southwest Airlines:

“Amazon Redshift RG instances have the potential to deliver meaningful business impact for Southwest Airlines. Based on initial testing in our development environment, our data warehouse workloads run 50-60% faster, and data lake analytics are 45% faster, enabling teams to get insights sooner, respond to operational conditions faster, and make data-driven decisions with less latency. These early results are encouraging, and we are excited to validate and scale these improvements in production. All of this comes without per-terabyte Spectrum scanning charges, delivering 30% lower cost than RA3 at a time when fuel prices continue to pressure industry margins.”

Akshay Srinivasan, Data Engineer, tombola:

“The new Graviton-based Amazon Redshift RG instances delivered 1.8x-2x faster write throughput and up to 2.2x faster read speeds compared to RA3 across a diverse set of batch and analytical jobs, enabling us to process 40% more within the same window. Compressed ETL cycles, accelerated time-to-insight, and decision-making no longer bottlenecked by the pipeline. Together, these translated directly into fresher data reaching our analysts and business teams sooner. What made this even more compelling was a concurrent 30% reduction in compute spend alongside the gains. Delivering more for less is a rare outcome, and one worth highlighting. In a volume-heavy gaming industry at tombola, where query latency and cost compound at scale, this has been one of the more impactful platform decisions we’ve made this year.”

Modernizing your workloads to RG

Today, we are launching rg.xlarge and rg.4xlarge instance sizes, available now for you to modernize your existing Amazon Redshift provisioned workloads. RG instances support three migration paths, all accessible directly from the AWS Management Console:

  • Elastic Resize (recommended): The fastest path for most customers migrating from RA3 or DC2, with only 10-15 minutes of downtime.
  • Snapshot & Restore: Best for you if you need to make configuration changes as part of your migration.
  • Classic Resize: Available for workloads that require a full cluster rebuild.

Before migrating your production workloads, we strongly recommend validating your queries and workloads on RG instances first. We’ve published an Upgrade Guide to help you right-size your cluster and plan your migration with confidence.

Getting started

You can start using the RG instances (rg.xlarge and rg.4xlarge) today in the following AWS Regions: US East (N. Virginia), US East (Ohio), US West (Oregon), US West (N. California), Canada (Central), South America (São Paulo), Europe (Ireland), Europe (Frankfurt), Europe (London), Europe (Paris), Europe (Stockholm), Europe (Milan), Europe (Spain), Asia Pacific (Tokyo), Asia Pacific (Seoul), Asia Pacific (Singapore), Asia Pacific (Sydney), Asia Pacific (Mumbai), Asia Pacific (Jakarta), Asia Pacific (Hong Kong), Asia Pacific (Osaka), Asia Pacific (Malaysia), Asia Pacific (Hyderabad), Asia Pacific (Taipei), and Asia Pacific (Melbourne).

You can launch new clusters or migrate existing clusters through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS API.

To create a new RG cluster in the Amazon Redshift console

  1. Review the Cluster and Nodes in the Amazon Redshift documentation.
  2. Choose Amazon Redshift on the AWS Management Console and choose Create Cluster.
  3. In the Create Cluster screen, choose the required RG node type.

Amazon Redshift console showing the Create Cluster screen with RG node type selection

To modernize from RA3 or DC2 in the Amazon Redshift console

  1. Review the Upgrade Guide in the Amazon Redshift documentation.
  2. Choose your migration path. Elastic Resize is the right starting point for most customers.
  3. Choose the required RG node type.

Amazon Redshift console showing the Elastic Resize option for migrating to RG instances

Amazon Redshift console showing the node type selection during resize

Amazon Redshift console showing the resize confirmation screen

For pricing details, visit the Amazon Redshift pricing page.

Clean up

If you are evaluating RG instances in a test or development environment and do not wish to continue, you can delete your RG cluster directly from the AWS Management Console or by using the AWS CLI to avoid incurring additional charges. If you used Snapshot & Restore to create a test RG cluster alongside your existing RA3 cluster, make sure you delete the RG cluster and any associated snapshots you no longer need. If you are using Data Sharing during migration, remember to remove data shares and decommission your RA3 cluster after you have fully validated your workloads on RG.

Conclusion

Amazon Redshift RG instances represent a significant step forward for you if you run data warehouse and data lake workloads on AWS. By bringing AWS Graviton processors to Amazon Redshift Provisioned clusters for the first time, paired with a purpose-built vectorized native data lake engine, RG instances deliver up to 2.4x better performance on Iceberg workloads, up to 1.5x on Parquet, and up to 2.2x on RMS data warehouse workloads, all at 30% lower per-vCPU cost than RA3. The elimination of Amazon Redshift Spectrum scanning charges makes data lake query costs predictable for the first time.

To get started with RG instances, visit the Amazon Redshift RG documentation to assess your workload and plan your migration.

Resources

Questions or feedback? Drop a comment or join the discussion on AWS re:Post.


About the authors

Ankit Sahu

Ankit Sahu brings over 18 years of expertise in building innovative data products and services. His diverse experience spans product strategy, go-to-market execution, and digital transformation initiatives. Currently, as Sr. Product Manager at Amazon Web Services (AWS), Ankit is driving the vision and strategy for Amazon Redshift.

Amazon Redshift introduces AWS Graviton-based RG instances with an integrated data lake query engine

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/amazon-redshift-introduces-aws-graviton-based-rg-instances-with-an-integrated-data-lake-query-engine/

Since 2013, Amazon Redshift has given the full power of a data warehouse in the cloud, at a fraction of the on-premises cost. Every architectural generation—from dense compute to Amazon RA3 instances, from provisioned to Amazon Redshift Serverless—has made each query cheaper, faster, and more efficient than the last.

For over a decade, as data volumes have grown and analytics requirements have evolved, organizations increasingly leverage both data warehouse tables for structured, frequently-accessed data and data lakes for cost-effective storage of diverse datasets. Add AI agents to the mix and they query your data warehouse at a scale that dwarfs typical human usage, leading to spiraling operational costs.

Amazon Redshift has doubled down on its core strengths to meet the demands of any workload — whether driven by humans or AI agents. For example, in March 2026, Amazon Redshift improved the performance of business intelligence (BI) dashboards and ETL workloads by speeding up new queries by up to 7 times. This significantly improves the response times of low-latency SQL queries, such as those used in near-real-time analytics applications, BI dashboards, ETL pipelines, and autonomous, goal-seeking AI agents.

Today, we’re announcing Amazon Redshift RG instances, a new instance family powered by AWS Graviton. RG instances deliver better performance, running data warehouse workloads up to 2.2x as fast as RA3 instances at 30% lower price per vCPU. Their integrated data lake query engine lets you run SQL analytics across your data warehouse and data lake from a single engine with performance up to 2.4x as fast as RA3 for Apache Iceberg and up to 1.5x as fast as RA3 for Apache Parquet. This blend of speed, cost efficiency, and an integrated data lake query engine makes Redshift RG instances well-suited to handle the high query volumes and low-latency requirements of today’s analytics and agentic AI workloads.

You can compare new RG instances and current RA3 instances:

Current RA3 Instance Recommended RG instance vCPU Memory (GB) Primary Use Case
ra3.xlplus rg.xlarge 4 32 Small cluster departmental analytics
ra3.4xlarge rg.4xlarge 12 → 16 (1.33:1) 96 GB → 128 GB (1.33:1) Standard production workloads, medium data volumes

This approach reduces total analytics costs for customers running combined data warehouse and data lake workloads, while simplifying operations through a single system for querying both warehouse tables and Amazon Simple Storage Service (Amazon S3) data lakes. We recommend using the AWS Pricing Calculator with your specific workload patterns to estimate savings.

Getting started with Amazon Redshift RG instances
You can launch new clusters or migrate existing clusters through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS API. The integrated data lake query engine is enabled by default.

In the Amazon Redshift console, you can choose new RG instances when you create a cluster.

You can migrate previous-generation instances to RG instances with optimal paths based on your cluster configuration to estimate costs, validate compatibility, and automate execution.

  • Elastic Resize—in-place migration with 10-15 minutes downtime for compatible configurations
  • Snapshot and Restore—create a RG cluster from an RA3 snapshot. This is best for customers who want to make configuration changes during the migration

Your external tables, schemas, and query syntax—including existing Spectrum queries—remain unchanged. There is no need to recreate external tables or modify application code. To learn more, visit the Redshift Management Guide.

Amazon Redshift now executes data lake queries on cluster nodes—the same compute that processes data warehouse workloads. As a result, Amazon Redshift Spectrum is no longer required. Data lake queries stay within your VPC boundary, use existing IAM roles, and incur zero per-terabyte scanning charges. This removes the $5/TB Spectrum scanning fees that previously added to total Redshift costs.

Now available
Amazon Redshift RG instances are now available in the following AWS Regions: US East (N. Virginia, Ohio), US West (N. California, Oregon), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Malaysia, Melbourne, Mumbai, Osaka, Seoul, Singapore, Sydney, Taiwan, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, Milan, London, Paris, Spain, Stockholm), Middle East (UAE), and South America (São Paulo). For Regional availability and a future roadmap, visit the AWS Capabilities by Region. For Redshift Provisioned, you can select On-Demand Instances with hourly billing and no commitments or choose Reserved Instances for cost savings. To learn more, visit the Amazon Redshift Pricing page.

Give RG instances a try in the Redshift console and send feedback to AWS re:Post for Amazon Redshift or through your usual AWS Support contacts.

— Channy

How potential performance upside with AWS Graviton helps reduce your costs further

Post Syndicated from Markus Adhiwiyogo original https://aws.amazon.com/blogs/compute/how-potential-performance-upside-with-aws-graviton-helps-reduce-your-costs-further/

Amazon Web Services (AWS) provides many mechanisms to optimize the price performance of workloads running on Amazon Elastic Compute Cloud (Amazon EC2), and the selection of the optimal infrastructure to run on can be one of the most impactful levers. When we started building the AWS Graviton processor, our goal was to optimize AWS Graviton features and capabilities to deliver a processor that provides the best price performance across a broad array of cloud workloads running on Amazon EC2. That goal continues to be our guiding principle, and today customers who adopt AWS Graviton-based EC2 instances see up to 40% better price performance on their cloud workloads when compared to equivalent non-Graviton EC2 instances. The price performance improvement is the result of both the performance improvement and the lower price in using AWS Graviton-based instances.

Price performance blends the cost of infrastructure with the amount of work you can achieve with infrastructure usage. After talking to many AWS Graviton customers, we’ve learned that the cost savings go beyond the lower AWS Graviton-based instances price. Many AWS Graviton customers told us that the performance increase from AWS Graviton allows them to consume fewer computing hours than comparable non-Graviton instances for equivalent workload throughput. In turn, this leads to further cost reduction.

The following are some of examples from our customers:

  • Pinterest achieved 47% cost savings and 38% savings on compute resources while reducing carbon emissions by 62% for its web API workload.
  • SAP powers its SAP HANA Cloud with AWS Graviton to enhance its price performance by 35% while lowering carbon impact by 45%.
  • Sprinklr improved their machine learning (ML) inference workloads’ throughput by up to 20% while reducing costs by up to 25%.

You can find more customer examples in the AWS Graviton testimonials page.

To help organizations capture similar benefits, we’ve enhanced the AWS Graviton Savings Dashboard (GSD) with new features that account for both pricing and performance improvements. In the following section we explore these new capabilities and how they can help optimize your infrastructure costs.

Understanding performance-driven cost optimization in the GSD

The GSD helps organizations identify ideal workloads for AWS Graviton migration through automated resource matching and data-driven visualizations. You can learn the GSD details and setup in this AWS compute post.

Although the dashboard has traditionally focused on calculating direct cost savings from the AWS Graviton pricing advantages, we’ve observed that customers often experience more benefits when their applications perform more efficiently on AWS Graviton processors, leading to decreased compute resource usage. To better reflect these real-world scenarios, we’ve enhanced the dashboard with new features highlighting Normalized Instance Hours (NIH) analysis capabilities so that you can model potential savings based on both pricing benefits and compute hour reductions. Although this tool helps estimate potential savings, actual performance improvements can only be determined by testing your specific workloads on AWS Graviton instances. Performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Key dashboard components

This section outlines the following three key dashboard components: NIH reduction analysis, enhanced cost analysis visualizations, and detailed savings analysis.

NIH reduction analysis

The dashboard now features a new slider that lets you model potential cost savings by inputting the percentage reduction in NIH. Many organizations have found it challenging to calculate their total possible savings since the benefits come from two sources: the lower instance pricing of AWS Graviton and the reduced compute hours.

You can use the slider to model different cost scenarios by adjusting a theoretical NIH reduction between 0% and 40%. You can use this slider to input NIH reductions validated through your workload testing, model the combined impact of both pricing benefits and reduced compute hours, and explore different scenarios to help prioritize which workloads to test first.

Figure 1: NIH slider location

Figure 1: NIH slider location

Assume that your testing shows that your workload runs just as effectively with 15% fewer normalized instance hours on AWS Graviton. You can now plug that exact number into the slider to see your modeled savings combining both pricing differences and compute hour reductions. Although we’ve heard success stories of significant reductions from customers, we recommend starting your initial estimate with a conservative 10% baseline and adjusting based on your own testing results.

Enhanced cost analysis visualizations

The dashboard presents key visualizations that demonstrate the direct relationship between NIH reduction and cost savings. First, you see the Potential Graviton Base Savings from pricing differences alone. In the following diagram, we can observe an example of $61.54K of cost savings from migrating to equivalent AWS Graviton instances. Next, the Estimated Additional Savings Due to Performance in the same diagram shows $42.40K in savings if your performance testing confirms a 15% NIH reduction in your workload. Finally, the dashboard sums these two values into the Total Potential Graviton Savings of $103.94K. The Total Potential Graviton Savings helps visualize how both pricing benefits and any validated compute hour reductions could contribute to your overall savings.

Figure 2: Visualization with relationship between NIH reduction and cost savings

Figure 2: Visualization with relationship between NIH reduction and cost savings

The Amortized Cost Breakdown and Normalized Instance Hrs Breakdown charts in the following figure show 6-month historical trends, helping you spot patterns such as seasonal spikes or high-usage periods. These patterns can help you identify where even small efficiency improvements might yield significant savings, for example, workloads with consistently high usage or predictable peak periods that would be good candidates for testing.

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Figure 3: Amortized Cost, NIH, and Total Potential Savings Breakdown charts

Detailed savings analysis

Building on our commitment to help customers optimize cloud costs, we’ve enhanced the Potential Graviton Savings Details table with two columns focused on performance-based savings modeling. The Estimated Additional Savings Due to Performance column shows the modeled savings based on your chosen NIH reduction percentage, while Total Potential Graviton Savings combines this with the base pricing benefits.

Figure 4: Potential Graviton Savings Details table

Figure 4: Potential Graviton Savings Details table

As you examine your current instance family, you can observe both baseline AWS Graviton savings and these added saving opportunities clearly laid out in a comprehensive breakdown. The analysis presents your total savings potential in both dollar amounts and percentages. This allows you to build a compelling business case for migration. Although this detailed breakdown provides valuable planning insights, remember that actual savings may vary depending on your specific workload patterns, implementation approaches, and operational considerations.

Conclusion

The Graviton Savings Dashboard (GSD) serves as a powerful analytics tool that streamlines your journey to cost-effective cloud computing. The GSD provides clear visualizations and interactive features to help you understand and maximize potential savings when migrating to AWS Graviton-based instances. To further explore the new features, navigate to the GSD interactive demo, where you can model an example of potential savings using the NIH reduction slider and detailed cost breakdowns.

Ready to explore how AWS Graviton can transform your infrastructure costs? Visit the GSD page to deploy or update your GSD dashboard. Access implementation guides, such as the CFM Technical Implementation Playbook (CFM TIPs), and start optimizing your cloud spend today with the enhanced capabilities of the GSD.

Over 85,000 AWS customers have discovered the benefits of AWS Graviton, with many completing their adoptions in just hours. We have created this resource guide so that you can accelerate your AWS Graviton adoption with minimal effort and enjoy significant price performance benefits.

“What I always tell customers is one week, one application, one engineer, and see what you can do. They always are pleasantly surprised by how much progress they can make. If you’re out there and you haven’t yet moved to AWS Graviton, what are you waiting for? Let’s make it happen!”

Dave Brown, VP, AWS Compute & ML Services

Important note about performance testing
The GSD does not attempt to estimate the potential NIH percent reduction or your workload’s performance when transitioned to AWS Graviton. You can use it to perform what-if analysis of your potential savings for a projected NIH percent reduction. In the absence of this variable, GSD only considers the price delta between instance types and misses an important contributor to the overall savings potential of AWS Graviton from the performance upside. Compute performance is always workload and use case specific, so we encourage you to test your AWS Graviton-based workloads using the Optimization and Performance Runbook to help you determine the actual possible NIH percent reduction.

Implementing advanced AWS Graviton adoption strategies across AWS Regions

Post Syndicated from Matt Howard original https://aws.amazon.com/blogs/compute/implementing-advanced-aws-graviton-adoption-strategies-across-aws-regions/

AWS Graviton Processors can offer cost savings, improved performance, and reduce your carbon footprint when using Amazon Elastic Compute Cloud (Amazon EC2) instances. When expanding your Graviton deployment across multiple AWS Regions, careful planning helps you navigate considerations around regional instance type availability and capacity optimization. This post shows how to implement advanced configuration strategies for Graviton-enabled EC2 Auto Scaling groups across multiple Regions, helping you maximize instance availability, reduce costs, and maintain consistent application performance even in AWS Regions with limited Graviton instance type availability.

Instance type flexibility strategies

One of the most effective strategies for maximizing Graviton availability is to be flexible across multiple instance types and families. Instance families (such as m7g, c7g, and r7g) group similar instances with different sizes, where each size offers proportionally more vCPUs and memory. When configuring EC2 Auto Scaling groups, aim for at least 10 instance types rather than limiting to just one or two specific types. EC2 Auto Scaling supports this flexibility through the mixed instances group, which allows you to specify multiple instance types in a single group. Consider this example AWS CloudFormation template snippet for an EC2 Auto Scaling group MixedInstancesPolicy that only specifies two Graviton instance types across two different families:

"MixedInstancesPolicy": {
  "Overrides": [
    {
      "InstanceType": "m7g.large"
    },
    {
      "InstanceType": "c7g.xlarge"
    }
  ]
}

This limited selection significantly reduces your ability to access available capacity pools. Assuming this workload needs a minimum of 2 vCPU and 8 GiB of memory, you can add these additional eight Graviton instance types: m6g.large, m8g.large, m6gd.large, m7gd.large, m8gd.large, c6g.xlarge, c6gd.xlarge, and c8g.xlarge. These allow you to meet the recommendation of being flexible across 10 instance types. While some of these instance types may have different price points, you can manage these cost implications through allocation strategies discussed later in this post.

To efficiently identify all compatible Graviton instance types available for your workload, you can use the GetInstanceTypesFromInstanceRequirements Amazon EC2 API. This approach removes the manual effort of researching and choosing individual instance types.

aws ec2 get-instance-types-from-instance-requirements \
--architecture-types arm64 \
--virtualization-types hvm \
--instance-requirements '{"VCpuCount": {"Min": 2,"Max":8}, "MemoryMiB": {"Min": 8000}, "InstanceGenerations":["current"]}' \
--region us-east-1

This example command returns dozens of compatible Graviton instance types across multiple families (c7g, c7gd, c7gn, m7g, m7gd, etc.), thus expanding your capacity options. An EC2 Auto Scaling group’s mixed instance policy can allow up to 40 instance types, thus you have more room for even greater flexibility.

After expanding your instance type selection, you need to configure how EC2 Auto Scaling chooses between the available instance types. The OnDemandAllocationStrategy CloudFormation property controls this behavior, offering two approaches: “lowest-price” and “prioritized”. With the “lowest-price” strategy, EC2 Auto Scaling launches instances from the lowest-priced capacity pool available:

"OnDemandAllocationStrategy": "lowest-price"

This strategy helps manage costs when you’ve included a variety of instance types. Even with expanded instance type flexibility, your workloads will automatically select the most cost-effective option from available capacity pools. Alternatively, you can use the “prioritized” strategy when you want more control over which instance types are chosen first:

"OnDemandAllocationStrategy": "prioritized"

Regional adaptation techniques

Not all AWS Regions have the same Graviton instance types available. Regional variation in instance type availability creates a challenge when deploying applications consistently across multiple AWS Regions. To handle these differences, expand your instance type flexibility beyond the minimum 10 types to make sure of sufficient options in each AWS Region where you operate.

To implement this flexibility across AWS Regions, you must determine which Graviton instance types are available in each target AWS Region. AWS provides several methods to access this information: check the Amazon EC2 Instance Types by Region documentation for a comprehensive list, use the DescribeInstanceTypeOfferings Amazon EC2 API to programmatically identify available types, or visit the EC2 Instance Types page in the AWS Management Console.

You can also run the GetInstanceTypesFromInstanceRequirements API across different AWS Regions to understand Regional differences. For example, running identical queries in the US East (N. Virginia) and Asia Pacific (Taipei) Regions reveals significant variations: over 70 compatible instance types in the US East (N. Virginia) and 27 in Asia Pacific (Taipei) Regions.

# Query for US East (N. Virginia)
aws ec2 get-instance-types-from-instance-requirements \
--architecture-types arm64 \
--virtualization-types hvm \
--instance-requirements '{"VCpuCount": {"Min": 2,"Max":8}, "MemoryMiB": {"Min": 8000}, "InstanceGenerations":["current"]}' \
--region us-east-1

# Query for Asia Pacific (Taipei)
aws ec2 get-instance-types-from-instance-requirements \
--architecture-types arm64 \
--virtualization-types hvm \
--instance-requirements '{"VCpuCount": {"Min": 2,"Max":8}, "MemoryMiB": {"Min": 8000}, "InstanceGenerations":["current"]}' \
--region ap-east-2

When operating across multiple AWS Regions, design a single mixed instance policy that works everywhere by including instance types available in all AWS Regions where you operate. Based on the previous query results, you might include these 10 instance types that are available in both AWS Regions: m6g.large, m7g.large, m6gd.large, m7gd.large, c6g.xlarge, c7g.xlarge, m6g.xlarge, m7g.xlarge, c6gn.xlarge, and m6gd.xlarge.

You should also span your EC2 Auto Scaling group across multiple Availability Zones (AZs) for greater resiliency and access to deeper capacity pools. To determine available AZs in your AWS Region, refer to the Availability Zones documentation or check your Amazon Virtual Private Cloud (Amazon VPC) to identify which AZs its subnets use through the DescribeSubnets Amazon EC2 API. Configure your EC2 Auto Scaling group to use all available AZs using the CloudFormation AWS::AutoScaling::AutoScalingGroup AvailabilityZones parameter:

"AvailabilityZones": [
  "us-west-2a",
  "us-west-2b",
  "us-west-2c",
  "us-west-2d",
]

Best practices for EC2 Spot Instances usage with Graviton-based instances

Although optimizing for regional availability and AZ distribution provides a strong foundation, further enhancing your Graviton deployment strategy with proper Amazon EC2 Spot Instances configuration can significantly improve cost efficiency without sacrificing reliability. When using Spot Instances with Graviton, you should implement strategies that maximize your chances of obtaining and maintaining capacity.

First, the Spot Instance Advisor provides valuable information about the interruption frequency of different instance types across AWS Regions. Use this tool to identify Graviton instance types with lower interruption rates in your target AWS Regions. Then, expand your mixed instance group to include these other instance types. Especially for Spot Instance workloads, maximize your instance type flexibility by specifying up to the full limit of 40 instance types for EC2 Auto Scaling groups mixed instance policies. This broad selection increases your chances of finding available Spot Instances capacity.

Beyond instance type selection, the allocation strategy you choose significantly impacts your ability to maintain Spot Instances capacity. Configure your Spot allocation strategy using the AWS::AutoScaling::AutoScalingGroup InstancesDistribution property with the SpotAllocationStrategy parameter set to price-capacity-optimized to choose Spot pools with the lowest interruption risk while still considering price:

"InstancesDistribution": {
  "SpotAllocationStrategy": "price-capacity-optimized"
}

For workloads that can benefit from more time beyond the standard two-minute Spot interruption notice, enable Capacity Rebalancing. This feature, configured using the AWS::AutoScaling::AutoScalingGroup CapacityRebalanceproperty, enables EC2 Auto Scaling to proactively respond to rebalance recommendations by launching a new Spot Instance before a running instance receives the two-minute Spot Instance interruption notice, which provides more time for graceful transitions:

"CapacityRebalance": true

For maximum flexibility and capacity access, consider mixing x86 and ARM architectures in your launch templates. Although the Graviton capacity pools are newer and sometimes smaller than their x86 counterparts, a mixed architecture approach makes sure that you can still launch instances even when one architecture has limited availability. For detailed instructions, refer to the AWS post: Supporting AWS Graviton2 and x86 instance types in the same Auto Scaling group.

Attribute-based instance type selection

Although mixed instance policies with explicit instance type lists provide excellent flexibility, AWS offers an even more powerful approach for dynamic instance selection: attribute-based instance type selection. This streamlines management by allowing you to specify the attributes your application needs rather than specific instance types, automatically adapting to new instance types and handling Regional differences in availability.

Implement attribute-based instance type selection in your EC2 Launch Template through the AWS::EC2::LaunchTemplate InstanceRequirements property:

{
  "InstanceRequirements": {
    "AcceleratorCount": {
      "Max": 0
    },
    "BareMetal": "excluded",
    "BaselinePerformanceFactors": {
      "Cpu": {
        "References": [
          {
            "InstanceFamily": "c7g"
          }
        ]
      }
    },
    "InstanceGenerations": [
      "current"
    ],
    "MemoryMiB": {
      "Min": 8000
    },
    "VCpuCount": {
      "Min": 4
    }
  }
}

The BaselinePerformanceFactors parameter of the AWS::EC2::LaunchTemplate InstanceRequirements property enables performance protection. This feature makes sure that your EC2 Auto Scaling group uses instance types that meet or exceed a specified performance baseline. When you specify an instance family such as “c7g” as the baseline reference, Amazon EC2 automatically excludes instance types that fall below this performance level, even if they match your other specified attributes. For Graviton deployments, specifying “c7g” makes sure that only instance types with performance like or better than Graviton3 processors are chosen.

Attribute-based instance type selection also allows you to specify instance types in your template that may not yet be available in an AWS Region by using the AllowedInstanceTypes parameter:

{
  "AllowedInstanceTypes": [
    "m6g.large",
    "m7g.large",
    "m8g.large"
  ]
}

This approach allows your EC2 Auto Scaling group to use newer instance types where available and automatically deploy them in other AWS Regions as soon as they become available. This single template approach simplifies the deployment and management of your EC2 instance selection in EC2 Auto Scaling groups across many regions.

Special considerations

The following special considerations should be taken into account.

Performance testing with multiple instance types

When implementing instance type flexibility, a common concern is the need to test all instance types with your application. Testing 40 different instance types isn’t practical for most organizations. Instead, consider these streamlined approaches to reduce testing overhead while maintaining performance confidence. First, Graviton instance families within the same generation (for example, c7g, m7g, and r7g) use the same processor, providing similar performance profiles across families. Therefore, you can include multiple instance types from the same generation after testing a representative instance. Second, you should also consider including variants within families (such as c7gd with NVMe storage), because these provide specialized capabilities without changing the fundamental CPU architecture. Third, for maximum flexibility, include multiple instance generations. If your application runs well on Graviton3, then it likely performs even better on Graviton4, allowing you to specify both in your EC2 Auto Scaling group.

Reserving specific Graviton instance types

If your workload needs a specific Graviton instance type, then we recommend that you use EC2 Capacity Reservations, which allow you to reserve compute capacity for EC2 instances in a specific AZ for any duration. On-Demand Capacity Reservations (ODCR) are for immediate use and come with no term commitment. Alternatively, Future-dated Capacity Reservations allow you to specify when you need the capacity to become available along with a commitment duration.

Amazon EMR workloads

Although Amazon EMR clusters must exist in only one AZ, you can use Amazon EMR instance fleets to choose multiple subnets across different AZs. Then, when launching a cluster, Amazon EMR searches across these subnets to find specified instances and purchasing options, thus providing access to a deeper capacity pool. For Instance Fleets you can specify up to 30 EC2 instance types for each primary, core, and task node group, which significantly improves instance flexibility and availability. For more information go to the Responding to Amazon EMR cluster insufficient instance capacity events documentation.

Conclusion

In this post, we covered advanced strategies for maximizing AWS Graviton adoption across multiple AWS Regions. You can use the AWS CloudFormation examples provided in this post as templates for your own implementations. Following these approaches allows you to maintain consistent application performance and maximize Graviton instance availability across all AWS Regions where you operate, even as Graviton availability continues to expand across the AWS global infrastructure. For comprehensive guidance on maximizing your Graviton deployment, explore the AWS Graviton Technical Guide.

Improve RabbitMQ performance on Amazon MQ with AWS Graviton3-based M7g instances

Post Syndicated from Vignesh Selvam original https://aws.amazon.com/blogs/big-data/improve-rabbitmq-performance-on-amazon-mq-with-aws-graviton3-based-m7g-instances/

Amazon MQ is a fully managed service for open-source message brokers such as RabbitMQ and Apache ActiveMQ. Today, we are announcing the availability of AWS Graviton3-based Rabbit MQ brokers on Amazon MQ, which runs on Amazon EC2 M7g instances. AWS Graviton processors are custom designed server processors developed by AWS to provide the best price performance for cloud workloads running on Amazon EC2. It uses the Arm (arm64) instruction set. For example, when running an Amazon MQ for RabbitMQ cluster broker using M7g.4xlarge instances, you can achieve up to 50% higher workload capacity and up to 85% higher throughput compared to M5.4xlarge instances. Additionally, M7g brokers on Amazon MQ offer optimized disk sizes for clusters, providing reduction in storage cost savings over M5 brokers depending on the instance size chosen. To learn more, refer to Amazon EC2 M7g instances.

Amazon MQ helps you reduce the operational overhead of using open source message brokers like RabbitMQ while providing security, high availability, and durability. Many organizations use Amazon MQ to decouple applications, asynchronously process messages, and build event-driven architectures. We tested and validated M7g instances for RabbitMQ version 3.13, so you can run your critical messaging workloads on Amazon MQ brokers with improved performance characteristics, while also saving on costs. Amazon MQ supports M7g instances in a wide variety of sizes, ranging from medium to 16xlarge sizes, to suit your different messaging workloads. M7g instances support Amazon MQ for RabbitMQ features, making it straightforward for you to run your existing RabbitMQ workloads with minimal changes. You can get started by provisioning new brokers or upgrading your existing RabbitMQ brokers using Amazon EC2 M5 instances to Graviton3-based M7g instances as the broker type using the AWS Management Console, APIs using the AWS SDK, and the AWS Command Line Interface (AWS CLI).

The following table lists the specific characteristics of M7g instances on Amazon MQ.

M7g specs for Amazon MQ
Instance Name (MQ.m7g.*) vCPUs Memory (GiB) Network Bandwidth
medium 1 4 Up to 12.5 Gb
large 2 8 Up to 12.5 Gb
xlarge 4 16 Up to 12.5 Gb
2xlarge 8 32 Up to 15 Gb
4xlarge 16 64 Up to 15 Gb
8xlarge 32 128 15 Gb
12xlarge 48 192 22.5 Gb
16xlarge 64 256 30 Gb

M7g instances vs. M5 instances on Amazon MQ

Customers can see both performance improvements and cost savings for their RabbitMQ workloads when moving from M5 instances to M7g instances. In terms of performance, you can size your RabbitMQ brokers for workloads by measuring the workload capacity and throughput. Amazon MQ has improved the performance of RabbitMQ on both workload capacity and throughput for M7g instances. In terms of cost, you pay for the instance per hour, disk usage per Gb-month, and data transfer. Amazon MQ has optimized disk sizes to offer cost savings for customers on disk usage. Let’s first examine the performance improvements.

Workload capacity improvements

Workload capacity represents the total number of connections, channels, and queues that you can use without running into memory alarm. The actual usage of these resources is limited by the high memory watermark value. Every resource (for example, a queue) on creation uses up a small amount of memory, but when these resources are used, the memory used increases depending on the number and size of messages processed up until a memory threshold. The RabbitMQ broker goes into memory alarm when the memory used on a node reaches this pre-defined threshold known as high memory watermark. When a broker raises a memory alarm, it will block all connections that are publishing messages. After the memory alarm has cleared (for example, due to delivering some messages to clients that consume and acknowledge the deliveries), normal service resumes. The open source community guidance for RabbitMQ 3.13 is to configure the memory threshold at 40% of the available memory per node. M5 brokers have the memory threshold set at 40% on Amazon MQ.

We evaluated this recommendation across M7g instances and determined that the memory threshold can be increased for instances on Amazon MQ to more than 40% due to the operational improvements by the service, as illustrated in the following figure. This increase in available memory translates to a higher use of resources like queues, channels, and connections within the resource limits of the broker. The change in available memory results in up to 50% improvement in workload capacity for customers when compared to M5 brokers today.

Throughput improvements

The throughput of a broker varies widely with the queue type and usage pattern of customers. Amazon MQ evaluated the throughput capacity of a RabbitMQ three-node cluster broker by measuring the publish throughput in messages per second for 10 quorum queues with a message size of 1 KB and a ratio of 1:20 for connection to channels. We arrived at this benchmark test after evaluating multiple scenarios with the goal of providing you a simple way to estimate the average throughput you can expect from a RabbitMQ broker when following best practices. You can see up to 85% higher throughput compared to equivalent M5 brokers on Amazon MQ, as illustrated in the following figure.

The performance of a RabbitMQ broker depends on the version, queue type, and usage pattern in addition to the infrastructure used. You might see different performance improvements based on your specific usage patterns and resources used. We recommend using the Amazon MQ sizing guidance to size your broker and benchmarking the performance for your specific workload using M7g instances.

Cost savings on cluster disk usage

Customers using M7g brokers in cluster deployment mode are provisioned with a disk volume per node that varies in size depending on the instance size. For M5 brokers, the RabbitMQ brokers were provisioned with a fixed disk volume of 200 GB per node. The open source guidance around disk sizes is to use a size higher than twice the memory threshold. We tested various disk sizes and identified optimal disk sizes that would provide a better operational posture. With this change, customers using M7g cluster brokers on Amazon MQ will get cost savings due to the smaller disk size provisioned per node as compared to equivalent M5 brokers, as shown in the following table. Single-instance M7g brokers will continue to be provisioned with 200 GB of disk size.

Instance size Disk Volume M5 cluster(GB) Disk Volume M7g Cluster(GB) Cost savings for customersM5 vs. M7g (%)
medium – 15 –
large 600 45 92.50%
xlarge 600 75 87.50%
2xlarge 600 135 77.50%
4xlarge 600 270 55.00%
8xlarge – 525 –
12xlarge – 780 –
16xlarge – 1035 –

Pricing and Regional availability

M7g instances are available in AWS Regions where Amazon MQ is available at the time of writing except Africa (Cape Town), Canada West (Calgary), and Europe (Milan) Regions. Refer to Amazon MQ Pricing to learn about the availability of specific instance sizes by Region and the pricing for M7g instances.

Summary

In this post, we discussed the performance gains and cost savings achieved while using Graviton-based M7g instances. These instances can provide significant improvement in throughput and workload capacity compared to similar sized M5 instances for Amazon MQ workloads. To get started, create a new broker with M7g brokers using the console, and refer to the Amazon MQ Developer Guide for more information.


About the authors

Vignesh Selvam is the Principal Product Manager for Amazon MQ at AWS. He works with customers to solve their messaging needs and with the open-source communities for innovating with message brokers. Prior to joining AWS, he built products for security and analytics.
Samuel Massé is a Software Development Engineer at AWS. He has been leading the engineering effort to support M7g on the RabbitMQ team. In his free time he enjoys coding unfinished side projects.
Vinodh Kannan Sadayamuthu is a Senior Specialist Solutions Architect at Amazon Web Services (AWS). His expertise centers on AWS messaging and streaming services, where he provides architectural best practices consultation to AWS customers.

New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/new-amazon-ec2-c8gn-instances-powered-by-aws-graviton4-offering-up-to-600gbps-network-bandwidth/

Today, we’re announcing the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C8gn network optimized instances powered by AWS Graviton4 processors and the latest 6th generation AWS Nitro Card. EC2 C8gn instances deliver up to 600Gbps network bandwidth, the highest bandwidth among EC2 network optimized instances.

You can use C8gn instances to run the most demanding network intensive workloads, such as security and network virtual appliances (virtual firewalls, routers, load balancers, proxy servers, DDoS appliances), data analytics, and tightly-coupled cluster computing jobs.

EC2 C8gn instances specifications
C8gn instances provide up to 192 vCPUs and 384 GiB memory, and offer up to 30 percent higher compute performance compared Graviton3-based EC2 C7gn instances.

Here are the specs for C8gn instances:

Instance Name vCPUs Memory (GiB) Network Bandwidth (Gbps) EBS Bandwidth (Gbps)
c8gn.medium 1 2 Up to 25 Up to 10
c8gn.large 2 4 Up to 30 Up to 10
c8gn.xlarge 4 8 Up to 40 Up to 10
c8gn.2xlarge 8 16 Up to 50 Up to 10
c8gn.4xlarge 16 32 50 10
c8gn.8xlarge 32 64 100 20
c8gn.12xlarge 48 96 150 30
c8gn.16xlarge 64 128 200 40
c8gn.24xlarge 96 192 300 60
c8gn.metal-24xl 96 192 300 60
c8gn.48xlarge 192 384 600 60
c8gn.metal-48xl 192 384 600 60

You can launch C8gn instances through the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs.

If you’re using C7gn instances now, you will have straightforward experience migrating network intensive workloads to C8gn instances because the new instances offer similar vCPU and memory ratios. To learn more, check out the collection of Graviton resources to help you start migrating your applications to Graviton instance types.

You can also visit the Level up your compute with AWS Graviton page to begin your Graviton adoption journey.

Now available
Amazon EC2 C8gn instances are available today in US East (N. Virginia) and US West (Oregon) Regions. Two metal instance sizes are only available in US East (N. Virginia) Region. These instances can be purchased as On-Demand, Savings Plan, Spot instances, or as Dedicated instances and Dedicated hosts.

Give C8gn instances a try in the Amazon EC2 console. To learn more, refer to the Amazon EC2 C8g instance page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— Channy

AWS Weekly Roundup: New AWS Heroes, Amazon Q Developer, EC2 GPU price reduction, and more (June 9, 2025)

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-new-aws-heroes-amazon-q-developer-ec2-gpu-price-reduction-and-more-june-9-2025/

The AWS Heroes program recognizes a vibrant, worldwide group of AWS experts whose enthusiasm for knowledge-sharing has a real impact within the community. Heroes go above and beyond to share knowledge in a variety of ways in developer community. We introduce our newest AWS Heroes in the second quarter of 2025.

To find and connect with more AWS Heroes near you, visit the categories in which they specialize Community Heroes, Container Heroes, Data Heroes, DevTools Heroes, Machine Learning Heroes, Security Heroes, and Serverless Heroes.

Last week’s launches
In addition to the inspiring celebrations, here are some AWS launches that caught my attention.

For a full list of AWS announcements, be sure to keep an eye on What’s New at AWS.

Other AWS news
Here are some additional projects, blog posts that you might find interesting:

  • Up to 45 percent price reduction for Amazon EC2 NVIDIA GPU-accelerated instances – AWS is reducing the price of NVIDIA GPU-accelerated Amazon EC2 instances (P4d, P4de, P5, and P5en) by up to 45 percent for On-Demand and Savings Plan usage. We are also making the very new P6-B200 instances available through Savings Plans to support large-scale deployments.
  • Introducing public AWS API models – AWS now provides daily updates of Smithy API models on GitHub, enabling developers to build custom SDK clients, understand AWS API behaviors, and create developer tools for better AWS service integration.
  • The AWS Asia Pacific (Taipei) Region is now open – The new Region provides customers with data residency requirements to securely store data in Taiwan while providing even lower latency. Customers across industries can benefit from the secure, scalable, and reliable cloud infrastructure to drive digital transformation and innovation.
  • Amazon EC2 has simplified the AMI cleanup workflow – Amazon EC2 now supports automatically deleting underlying Amazon Elastic Block Store (Amazon EBS) snapshots when deregistering Amazon Machine Images (AMIs).
  • The Lab where AWS designs custom chips – Visit Annapurna Labs in Austin, Texas—a combination of offices, workshops, and even a mini data center—where Amazon Web Services (AWS) engineers are designing the future of computing.

Upcoming AWS events
Check your calendars and sign up for these upcoming AWS events.

  • Join re:Inforce from anywhere – If you aren’t able to make it to Philadelphia (June 16–18), tune in remotely. Get free access to the re:Inforce keynote and innovation talks live as they happen.
  • AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. Register in your nearest city: Shanghai (June 19 – 20), Milano (June 18), Mumbai (June 19) and Japan (June 25 – 26).
  • AWS re:Invent – Mark your calendars for AWS re:Invent (December 1 – 5) in Las Vegas. Registration is now open
  • AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world: Mexico (June 14), Nairobi, Kenya (June 14) and Colombia (June 28)

That’s all for this week. Check back next Monday for another Weekly Roundup!

– Betty

Accelerate your AWS Graviton adoption with the AWS Graviton Savings Dashboard

Post Syndicated from aostan original https://aws.amazon.com/blogs/compute/accelerate-your-aws-graviton-adoption-with-the-aws-graviton-savings-dashboard/

This post is written by Rajani Guptan, Rosa Corley and Shankar Gopalan.

Are you looking to optimize your AWS infrastructure costs while maintaining high performance? AWS Graviton is a custom-built CPU developed by Amazon Web Services (AWS), and it is designed to deliver the best price performance for a broad range of cloud workloads running on Amazon Elastic Compute Cloud (Amazon EC2). Graviton-based instances provide up to 40% better price performance while using up to 60% less energy than comparable EC2 instances.

AWS users recognize that migrating existing workloads to Graviton-based instances results in better price performance. However, migrating to Graviton necessitates identifying comparable instance types, understanding the performance impacts, and estimating the savings opportunities. Furthermore, prioritizing and tracking migration efforts at scale across a diverse set of services such as Amazon EC2, Amazon Relational Database Service (Amazon RDS), Amazon ElastiCache, and Amazon OpenSearch can be challenging. Therefore, AWS has developed the AWS Graviton Savings Dashboard to help users address these complexities and accelerate their Graviton migration.

In this post, we walk you through the dashboard architecture, deployment steps, features, and capabilities. Whether you are an Executive, FinOps Practitioner, Product Owner, or in Engineering, you can use the dashboard to get the following:

  • Centralized visibility across accounts/workloads: The dashboard consolidates and tracks Graviton adoption across multiple management accounts, member accounts, and AWS Regions in a single view.
  • Graviton support across key AWS services: There are dedicated tabs allowing users to review current Graviton usage and potential savings across AWS compute and managed services.
  • Granular resource-level visibility for managed services: The dashboard provides granular resource level visibility for managed services such as Amazon RDS, ElastiCache, and OpenSearch.
  • Accurate savings and unit cost estimations: The dashboard provides accurate cost estimations for existing and comparable Graviton-based instance types by using the existing AWS Cost and Usage Report (CUR) data with the AWS public pricing API.
  • Categorization of migration effort: The dashboard categorizes Graviton migration opportunities into two main groups: Typically Easy and Requires Additional Planning, for EC2 instances. It also identifies Graviton-eligible resources for managed services, which may need version or database upgrades. This categorization helps users prioritize their engineering efforts for migration.

Architecture overview

The solution integrates AWS CUR, the AWS SDK, and AWS Public pricing API to generate comprehensive data on the usage, cost, and resource inventory. This data is stored in Amazon S3 and analyzed using Amazon Athena, providing deep insights into potential cost savings. Then, the results are visualized through Amazon QuickSight, enabling stakeholders to collaborate effectively and make informed, data-driven decisions, as shown in the following figure.

Graviton Savings Dashboard architecture diagram

Figure 1: Graviton Savings Dashboard architecture diagram

Although the solution typically costs between $50–$100 per month, the potential return on investment is substantial. The dashboard often identifies measurable cost savings that significantly outweigh its operational expenses. Moreover, it offers additional productivity benefits by streamlining the process of adopting Graviton, saving valuable time and effort for your team. For a detailed breakdown of the dashboard’s cost structure, we invite you to explore our comprehensive Graviton Savings Dashboard Cost Breakdown guide.

Deployment

The Graviton Savings Dashboard is part of the Cloud Intelligence Dashboards framework. You can deploy it using AWS CloudFormation Templates and a ‘cid-cmd’ command line tool. Prior to deploying the dashboard, make sure that you’ve met the prerequisites. These include the following:

  1. Setting up your AWS CUR: We highly recommend that you complete Steps 1 and 2 from the Cloud Intelligence Dashboard Deployment Guide. This makes sure that your CUR is set up with settings that allow for easy installation and troubleshooting if necessary.
  2. Setting up the Inventory Collector Module of the Optimization Data Collection lab: This provides automation to collect metadata and pricing for Amazon RDS, ElastiCache, and OpenSearch for all accounts in your AWS Organizations and AWS Regions.
  3. Preparing QuickSight: If you’re an existing QuickSight user, then you can skip this step. If not, then you must complete Step 3.1 to Prepare QuickSight.

When the prerequisites are in place, you can deploy the dashboard by running three simple commands (shown as follows) using a terminal application with permissions to run API requests in your AWS account.

python3 -m ensurepip --upgrade

pip3 install --upgrade cid-cmd

cid-cmd deploy --dashboard-id graviton-savings

For detailed instructions about the deployment and prerequisites, refer to the AWS Well-Architected Cost Optimization lab.

Examining the results: unlocking insights from your Graviton Savings Dashboard

Now that you’ve successfully deployed the dashboard, we can explore its powerful features and uncover valuable insights. As you read through this section, we encourage you to interact with your dashboard to familiarize yourself with the dashboard’s intuitive interface and functionality.

The Graviton Savings Dashboard is organized into service-specific tabs, each containing two key sections:

Current Graviton Usage and Savings (top section): This section highlights the tangible benefits you’ve already achieved by migrating workloads to Graviton. You can explore the following:

    • Monthly Graviton adoption trends
    • Usage distribution across different accounts, Regions, and processor types
    • Popular Graviton instance families
    • Unit cost trends
    • Realized Graviton savings

These metrics are calculated by comparing your Graviton usage to comparable non-Graviton instances, which provides a clear picture of your cost optimization efforts, as shown in the following figure.

Current Amazon EC2 Graviton Usage and Savings

Figure 2: Current Amazon EC2 Graviton Usage and Savings

Potential Graviton Savings Opportunities (bottom section): This section identifies areas where you can further optimize costs by adopting Graviton instances. It provides the following:

  • Actionable migration insights
  • Estimated implementation effort
  • Potential savings breakdowns by account, instance family/type, OS, and purchase option

These insights compare potential Graviton savings across various attributes, enabling targeted decision-making for future Graviton migrations and cost optimizations, as shown in the following figure.

Amazon EC2 Graviton Opportunity

Figure 3: Amazon EC2 Graviton Opportunity

Using dashboard insights: a FinOps team use case

In this section we explore a use case where you, as the lead of the Cloud Center of Excellence Team, use the insights from this dashboard to address concerns raised by your Chief Technology Officer (CTO).

Your CTO at your company approaches you with the following questions:

  1. Is our organization using the price-performance benefits of Graviton-based EC2 instances?
  2. How does our Graviton usage and spend and savings compare to other processor types within our overall EC2 compute spend?

Step 1: Initial analysis

You begin generating summary reports from the Current Graviton Usage (Figure 2) and Graviton Opportunity (Figure 3) sections of the dashboard. After reviewing these reports, the CTO asks you to engage with the Engineering team to evaluate potential opportunities for increasing Graviton coverage.

Step 2: Engaging with Engineering on Graviton Migration

When presenting the summary reports to the engineering manager, they expressed interest in understanding the effort level required for this project. This information can help them allocate resources and prioritize workloads, thus identifying what can be started in the short-term and what needs additional planning.

Step 3: Detailed analysis

As shown in the following figure, the Engineering team can focus on identifying candidate workloads with the most significant savings impact by segmenting the dashboard data by:

  • Implementation efforts
  • Linked accounts
  • Regions
  • Instance types
  • Operating systems

Amazon EC2 Graviton opportunity breakdown

Figure 4: Amazon EC2 Graviton opportunity breakdown

Furthermore, the team can use the dashboard to determine comparable Graviton-based instances for migration and their potential savings, as shown in the following figure.

Potential graviton Savings Details

Figure 5: Potential graviton Savings Details

Step 4: Tracking progress

Over time, the FinOps team and Engineering team can showcase the Graviton migration successes by highlighting the increasing Graviton coverage and realized savings using the dashboard’s charts (Figure 2).

Broader application:

Although this post primarily focuses on EC2 instance migration, the dashboard also provides similar insights for AWS managed services such as Amazon RDS, ElastiCache, and OpenSearch. Individual tabs with visualizations guide your Graviton adoption across these services, as shown in the following figure.

Potential graviton savings details

Figure 6: Graviton Savings Dashboard

As demonstrated by this use case, the Graviton Savings Dashboard enables various stakeholders in an organization to collaborate effectively, which leads to efficient outcomes and potential cost savings.

Conclusion

In summary, we showed how the Graviton Savings Dashboard provides clear insights into suitable workloads for Graviton migration, offers easy-to-understand visualizations for monitoring adoption, and automates resource matching and savings calculations. Streamlining the process of identifying and implementing cost-saving opportunities with Graviton-based instances means that the dashboard enables more informed decision-making about your AWS infrastructure. To learn more and get started with the Graviton Savings Dashboard, visit the Graviton Savings Dashboard page and take the first step toward more efficient and cost-effective cloud computing.