According to the latest State of Ransomware report from security firm Sophos, most organizations (73%) use backups to recover from a ransomware attack. In fact, only 4% of victims who paid ransoms actually got all of their data back, so companies are likely using backups to recover after attacks whether they pay ransoms or not.
Still, Sophos found that it took ransomware victims a month on average to recover from an attack. The lesson here: Backups are vital as part of a disaster recovery plan, but the actual “recovery”—how you get your business back online using that backup data—is just as important. Few businesses can survive the hit of weeks or months spent offline.
If you use Veeam to manage backups, recovering from ransomware is a whole lot easier. Using Backblaze Instant Recovery in Any Cloud, you can consider your disaster recovery playbook complete.
Enter: Backblaze Instant Recovery in Any Cloud
Backblaze Instant Recovery in Any Cloud is an infrastructure as code (IaC) package that makes ransomware recovery into a VMware/Hyper-V based cloud easy to plan for and execute.
Disaster recovery and business continuity planning typically elude otherwise savvy IT teams for one of two reasons:
The lift of recovery planning is put on the back burner by more immediate demands.
Disaster recovery solutions aren’t rightsized for your business.
With Instant Recovery in Any Cloud, businesses have an easy, flexible path to as-soon-as-possible disaster recovery, putting fast, affordable disaster recovery within reach for any IT team.
You can run a single command using an industry-standard automation tool to quickly bring up an orchestrated combination of on-demand servers, firewalls, networking, storage, and other infrastructure in phoenixNAP. The command draws data from Veeam® Backup & Replication backups immediately to your VMware/Hyper-V based environment, so businesses can get back online with minimal disruption or expense. Put simply, it’s an on-demand path to a rock solid disaster recovery plan that makes recovery planning accessible and appropriately provisioned for your business.
We’ll explain the why and how of this solution below.
“Most businesses know that backing up is critical for disaster recovery. But we see time and again that organizations under duress struggle with getting their systems back online, and that’s why Backblaze’s new solution can be a game changer.”
—Mark Potter, CISO, Backblaze
From 3-2-1 to Immutable Backups to Disaster Recovery
For many years, the 3-2-1 backup strategy was the gold standard for data protection, and its core principles remain true—keep multiple copies of data, maintain on-site copies for fast restores, and keep off-site copies for disaster recovery. However, bad actors have become much more sophisticated, targeting not just production data but backups as well.
The introduction of Object Lock functionality allowed businesses to protect their cloud backups from ransomware by making them immutable, meaning even the administrator who set the lock can’t modify, encrypt, or delete files. With immutable backups, you can access a working, uncorrupted copy of your data in case of an attack.
But implementing immutable backups is only the first step. The critical second step is using that data to get your business back up and running. The time to get back to business after an attack often depends on how quickly backup data can be brought online—more than any other factor. That’s what makes disaster recovery planning so important, even though it’s one of those tasks that often gets put off when you’re putting out the next fire.
“For more than 400,000 Veeam customers, flexibility around disaster recovery options is essential. They need to know not only that their backups are safe, but that they’re practically usable in their time of need. We’re very happy to see Backblaze offering instant restore for all backups to VMware and Hyper-V based cloud offerings to help our joint customers thrive during challenging times.”
—Andreas Neufert, Vice President of Product Management, Alliances, Veeam.
Disaster Recovery That Fits Your Needs
If you’ve done any research into disaster recovery planning services, you’ve probably noticed that most plans are built for enterprise customers with enterprise budgets. You typically pay for compute functionality on an ongoing basis so you can quickly spin up a server in case of an attack. Those compute servers essentially sit idle as an “insurance policy.” Instant Recovery in Any Cloud opens disaster recovery to a huge number of businesses that were left without affordable solutions.
Instead of paying for compute servers you’re not using, Backblaze Instant Recovery in Any Cloud allows you to provision compute power on demand in a VMware and Hyper-V based cloud. The capacity is always there from Backblaze and phoenixNAP, but you don’t pay for it until you need it.
You can also spin up a server in any compute environment you prefer, allowing you to implement a multi-cloud, vendor-agnostic disaster recovery approach rather than relying on just one platform or vendor. The solution is written to work with phoenixNAP, and can be customized for other compute providers without difficulty.
Finally, because the recovery is entirely cloud based, you can execute your recovery plan from anywhere you’re able to access your accounts. Even if your whole network is down, you can still get your recovery plan rolling.
For busy IT teams, this is essentially a cut and paste setup—an incredibly small amount of work to architect a recovery plan.
How It Works and What You Need
Instant Recovery in Any Cloud works through a pre-built code package your staff can use to create a digital mirror image of your on-premises infrastructure. The code package is built in Ansible, an open-source tool which enables IaC. Running an Ansible playbook allows you to provision and configure infrastructure and deploy applications as needed. All components are pre-configured within the script. In order to get started, you can find the appropriate instructions on our GitHub page.
If you haven’t already, you also need to set up Backblaze B2 Cloud Storage as part of a Scale-out Backup Repository with Immutability in Veeam using the Backblaze S3 Compatible API, and your data needs to be backed up securely before deploying the command.
If you follow the latest ransomware developments, you know disaster recovery is something your business needs now more than ever. With tools like Object Lock and Backblaze Instant Recovery in Any Cloud, it doesn’t have to be complicated and costly. Protect your backups with Object Lock immutability, and keep the Ansible playbook and instructions on hand as part of a bigger ransomware recovery plan so that you’re ready in the event of an attack. Simply spin up servers and restore backups in a safe environment to minimize disruption to your business.
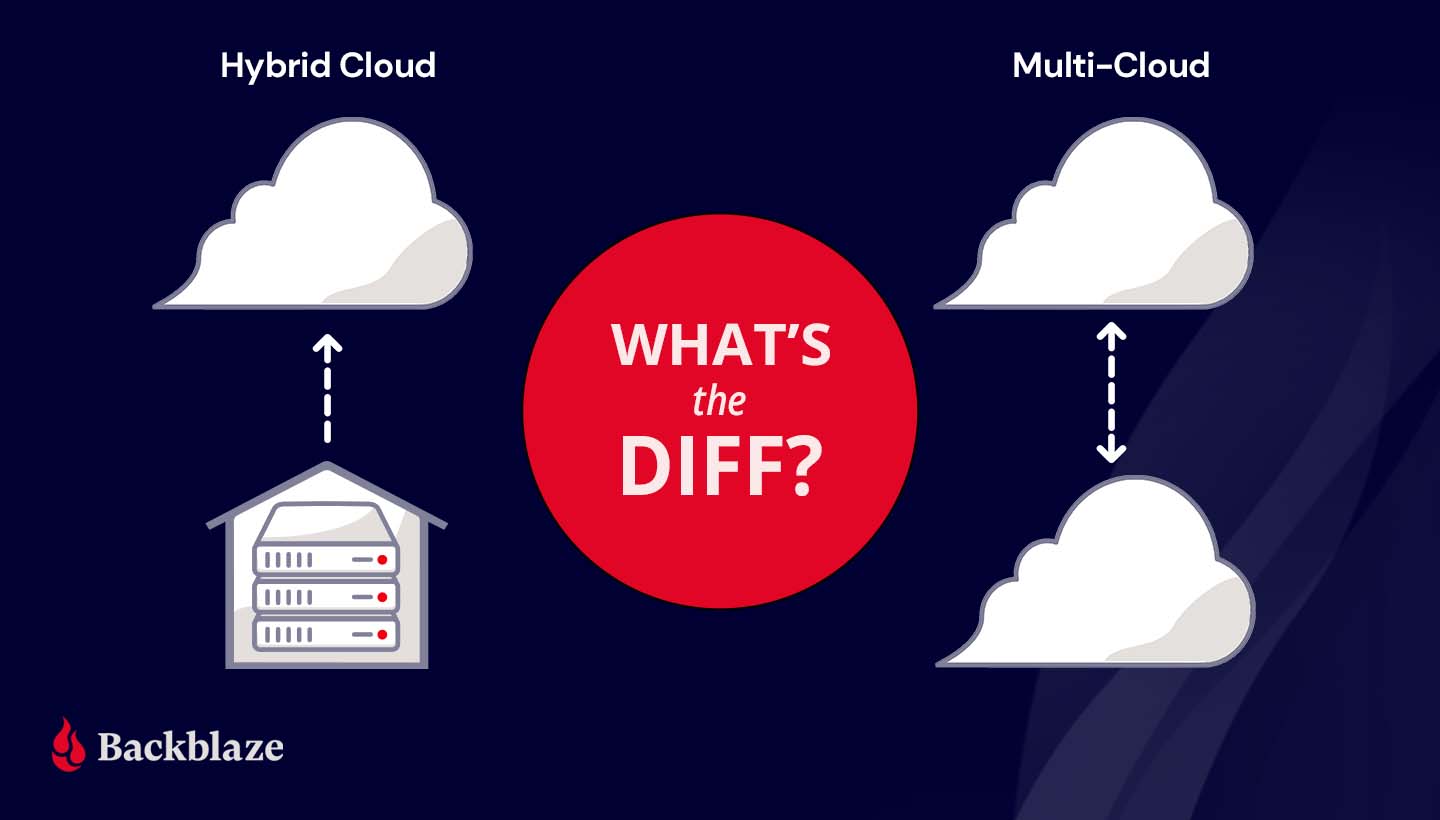
For as often as the terms multi-cloud and hybrid cloud get misused, it’s no wonder the concepts put a lot of very smart heads in a spin. The differences between a hybrid cloud and a multi-cloud strategy are simple, but choosing between the two models can have big implications for your business.
In this post, we’ll explain the difference between hybrid cloud and multi-cloud, describe some common use cases, and walk through some ways to get the most out of your cloud deployment.
What’s the Diff: Hybrid Cloud vs. Multi-cloud
Both hybrid cloud and multi-cloud strategies spread data over, you guessed it, multiple clouds. The difference lies in the type of cloud environments—public or private—used to do so. To understand the difference between hybrid cloud and multi-cloud, you first need to understand the differences between the two types of cloud environments.
A public cloud is operated by a third party vendor that sells data center resources to multiple customers over the internet. Much like renting an apartment in a high rise, tenants rent computing space and benefit from not having to worry about upkeep and maintenance of computing infrastructure. In a public cloud, your data may be on the same server as another customer, but it’s virtually separated from other customers’ data by the public cloud’s software layer. Companies like Amazon, Microsoft, Google, and us here at Backblaze are considered public cloud providers.
A private cloud, on the other hand, is akin to buying a house. In a private cloud environment, a business or organization typically owns and maintains all the infrastructure, hardware, and software to run a cloud on a private network.
Private clouds are usually built on-premises, but can be maintained off-site at a shared data center. You may be thinking, “Wait a second, that sounds a lot like a public cloud.” You’re not wrong. The key difference is that, even if your private cloud infrastructure is physically located off-site in a data center, the infrastructure is dedicated solely to you and typically protected behind your company’s firewall.
What Is Hybrid Cloud Storage?
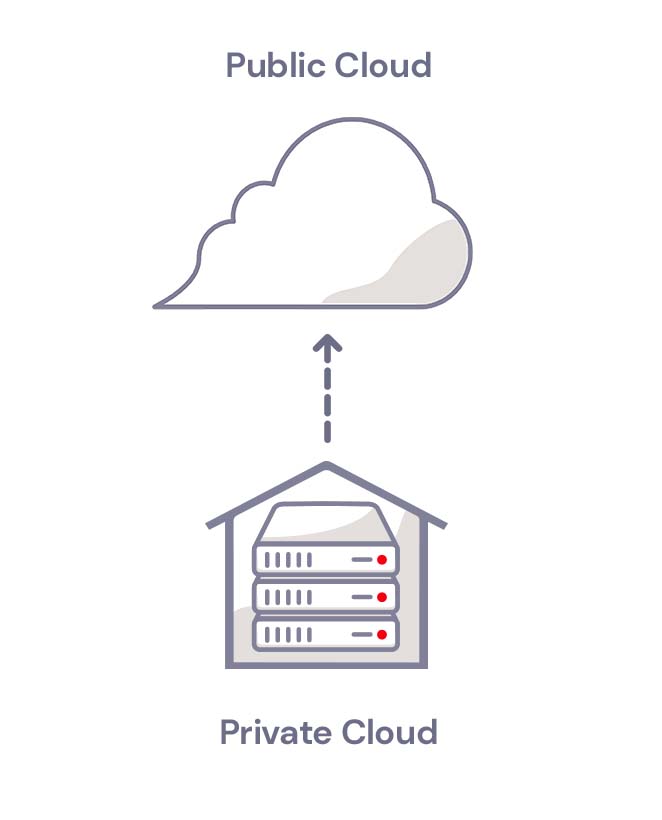
A hybrid cloud strategy uses a private cloud and public cloud in combination. Most organizations that want to move to the cloud get started with a hybrid cloud deployment. They can move some data to the cloud without abandoning on-premises infrastructure right away.
A hybrid cloud deployment also works well for companies in industries where data security is governed by industry regulations. For example, the banking and financial industry has specific requirements for network controls, audits, retention, and oversight. A bank may keep sensitive, regulated data on a private cloud and low-risk data on a public cloud environment in a hybrid cloud strategy. Like financial services, health care providers also handle significant amounts of sensitive data and are subject to regulations like the Health Insurance Portability and Accountability Act (HIPAA), which requires various security safeguards where a hybrid cloud is ideal.
A hybrid cloud model also suits companies or departments with data-heavy workloads like media and entertainment. They can take advantage of high-speed, on-premises infrastructure to get fast access to large media files and store data that doesn’t need to be accessed as frequently—archives and backups, for example—with a scalable, low-cost public cloud provider.
Hybrid Cloud
What Is Multi-cloud Storage?
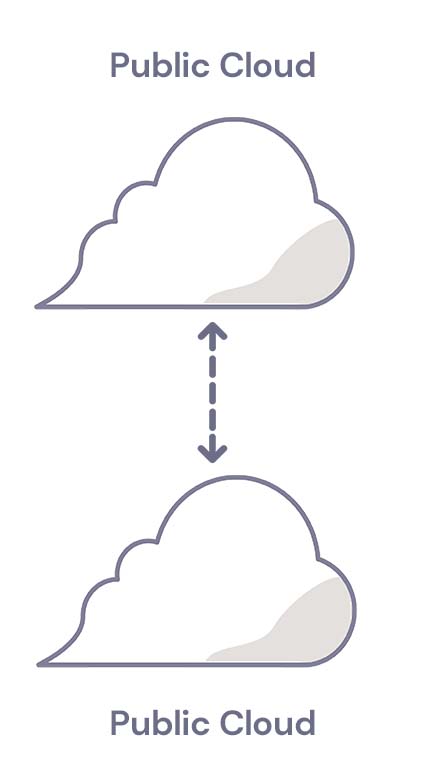
A multi-cloud strategy uses two or more public clouds in combination. A multi-cloud strategy works well for companies that want to avoid vendor lock-in or achieve data redundancy in a failover scenario. If one cloud provider experiences an outage, they can fall back on a second cloud provider.
Companies with operations in countries that have data residency laws also use multi-cloud strategies to meet regulatory requirements. They can run applications and store data in clouds that are located in specific geographic regions.
Whether you use hybrid cloud storage or multi-cloud storage, it’s vital to manage your cloud deployment efficiently and manage costs. To get the most out of your cloud strategy, we recommend the following:
Know your cost drivers. Cost management is one of the biggest challenges to a successful cloud strategy. Start by understanding the critical elements of your cloud bill. Track cloud usage from the beginning to validate costs against cloud invoices. And look for exceptions to historical trends (e.g., identify departments with a sudden spike in cloud storage usage and find out why they are creating and storing more data).
Identify low-latency requirements. Cloud data storage requires transmitting data between your location and the cloud provider. While cloud storage has come a long way in terms of speed, the physical distance can still lead to latency. The average professional who relies on email, spreadsheets, and presentations may never notice high latency. However, a few groups in your company may require low latency data storage (e.g., HD video editing). For those groups, it may be helpful to use a hybrid cloud approach.
Optimize your storage. If you use cloud storage for backup and records retention, your data consumption may rise significantly over time. Create a plan to regularly clean your data to make sure data is being correctly deleted when it is no longer needed.
Prioritize security. Investing up-front time and effort in a cloud security configuration pays off. At a minimum, review cloud provider-specific training resources. In addition, make sure you apply traditional access management principles (e.g., deleting inactive user accounts after a defined period) to manage your risks.
How to Choose a Cloud Strategy
To decide between hybrid cloud storage and multi-cloud storage, consider the following questions:
Low latency needs. Does your business need low latency capabilities? If so, a hybrid cloud solution may be best.
Geographical considerations. Does your company have offices in multiple locations and countries with data residency regulations? In that case, a multi-cloud storage strategy with data centers in several countries may be helpful.
Regulatory concerns. If there are industry-specific requirements for data retention and storage, these requirements may not be fulfilled equally by all cloud providers. Ask the provider how exactly they help you meet these requirements.
Cost management. Pay close attention to pricing tiers at the outset, and ask the provider what tools, reports, and other resources they provide to keep costs well managed.
Still wondering what type of cloud strategy is right for you? Ask away in the comments.
Storage technology has certainly changed over time, with new storage mediums taking aim at what’s become the industry standard: the hard disk drive (HDD). Of all the challengers, solid state drives (SSDs) are the most widely-adopted and likely to take the top spot—they’re fast, quiet, and retain information when they’re powered off (so you can just pop open your laptop and get back in the groove).
Yes, they’re more expensive than traditional hard disk drives, but there’s value in their much faster read/write speeds, and they’re arguably more reliable depending on your use case in the long term. Even with those benefits, that’s not to say HDDs are obsolete, just that there is good reason to upgrade to SSDs in many cases. The decision from the judges: These two contenders get to share the spotlight, and you get to decide which drive works best for your needs.
Once you’ve made the decision to invest in an SSD, you’ll have to choose the form factor and possibly the interface. In this post we’ll cover some basics about SSDs that should help you choose which type of SSD is best for you, including:
What is an SSD?
What is a SATA SSD?
What is an M.2 SSD?
What is an MSATA SSD?
What is an U.2 SSD?
What is an NVMe SSD?
Which SSD is right for you?
A Brief Introduction to SSDs
SSDs are storage devices that use NAND-based flash memory to store data. They are now standard issue for most computers, as is the case across Apple’s line of Macs. Unlike traditional hard disk drives (HDDs), which store data on spinning disks, SSDs have no moving parts, which makes them faster, more reliable, and less prone to mechanical failures.
SSDs have become so common mainly because they are faster in terms of read/write speeds versus hard drives. This means that they can access and transfer data much more quickly. This makes them an ideal choice for use in high-performance computers, servers, and other devices that require fast data access and transfer speeds. They also use less power and are available at different form factors, such as 2.5” and M.2, so they can be used in a range of devices. You can read more about the difference between SSDs and HDDs in this post.
One downside of SSDs is that they tend to be more expensive than HDDs, especially when it comes to larger storage capacities. However, as the cost of flash memory continues to decrease, SSDs are becoming more affordable and accessible for everyday consumers. Comparatively speaking, they also have a more limited write cycle. While you usually don’t run into this limitation as a typical computer user, if you’re constantly saving large files like you would if you’re working with media files, for instance, it’s something to consider.
Additionally, it can be harder to tell when an SSD is failing (no spinning disks to whir furiously at you), which means you’ll want to make sure you’re effectively monitoring your drives and backing up.
What Is a SATA SSD?
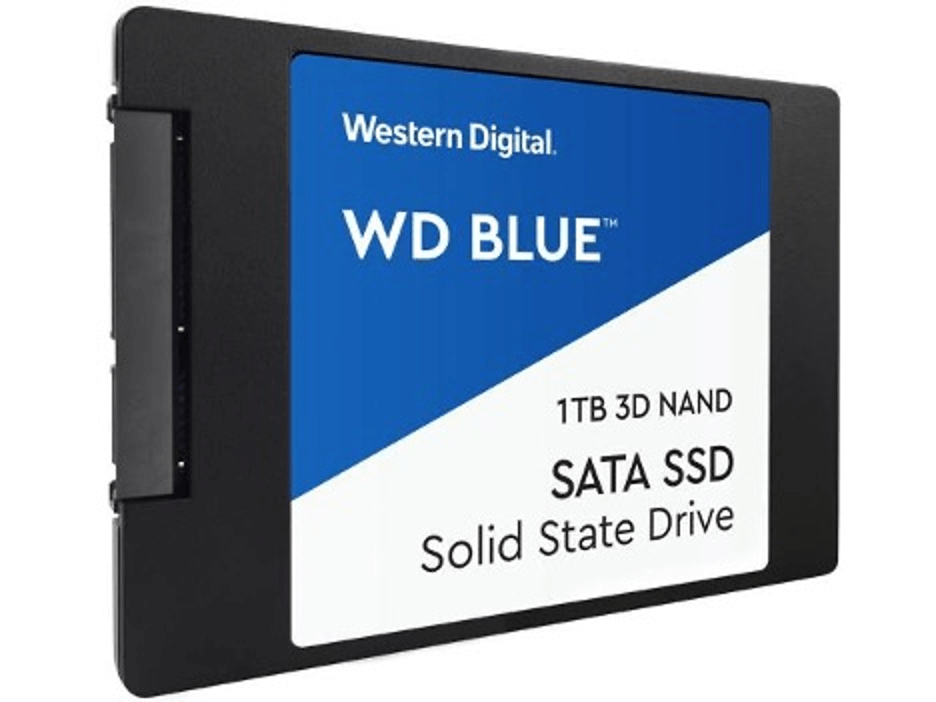
A Serial Advanced Technology Attachment (SATA) is the standard storage interface used in many computers. A SATA SSD is an SSD equipped with a SATA interface to connect the storage device to a computer’s motherboard. The SATA SSD comes in the standard 2.5 inch form factor and has both power and data (SATA) connectors. If you buy an SSD external drive to connect to your PC, there will most likely be a SATA SSD inside.
Generally, the SATA SSD is the least expensive type of SSD, all other factors being equal. This makes a great choice to get an instant performance boost out of your HDD-based computer, or add an external drive that can read and write data more quickly.
One thing to know about external SSD drives is that they should not be disconnected from your computer and stored away for long periods of time. Anything over a year is too long, and as the drive gets older it needs to be plugged in even more often. If you do want to use your SSD for long-term archival storage and have it disconnected from your main devices (air gap, anyone?), then it’s a good idea to either store them with about 50% charge, or power on the SSD every few months to refresh the charge.
What Is an NVMe?
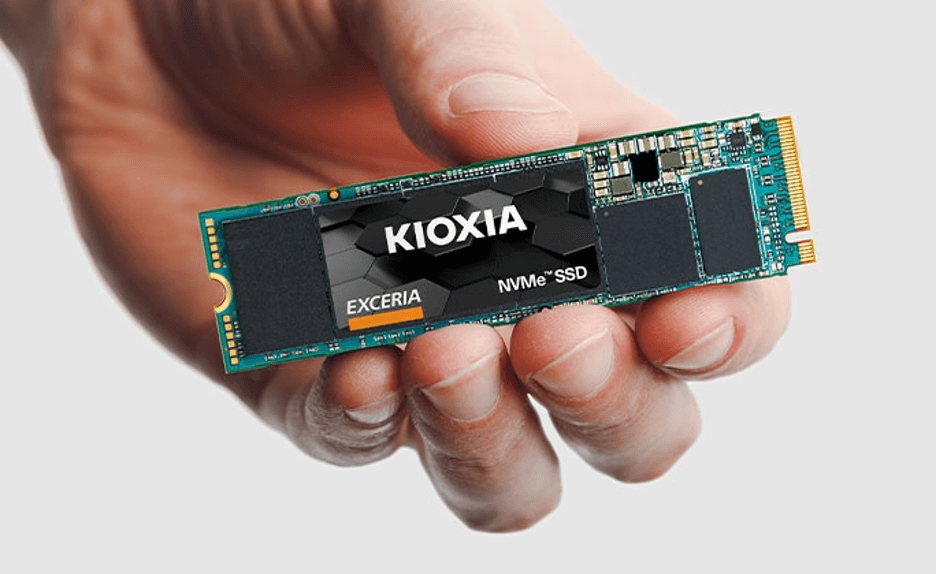
Non-Volatile Memory Express (NVMe) is a storage protocol that offers high-speed and efficient communication between a computer’s CPU and SSDs. Drives that use NVMe were introduced in 2013 to attach to the Peripheral Component Interconnect Express (PCIe) slot directly on a motherboard instead of using the traditional SATA interface typically used by HDDs and older SSDs. Unlike SATA, which was originally designed for slower HDDs, NVMe takes advantage of the low-latency and high-speed capabilities of SSDs. NVMe drives can usually deliver a sustained read-write speed of 4.0 GB/s in contrast with SATA SSDs that limit at 600 MB/s. Since NVMe SSDs can reach higher speeds and handle multiple data transfers simultaneously, it makes them ideal for gaming, high-resolution video editing, and applications that require high-performance storage, such as enterprise databases, virtualization, and data analytics.
Their high speeds come at a high cost, however: NVMe drives are some of the more expensive drives on the market.
To sum up our analysis on storage protocols in SSDs, here’s a handy chart:
Feature
SATA
NVMe
Interface
Serial Advancement Technology Attachment
Non-Volatile Memory Express
Bus
SATA bus
PCIe bus
Data Transfer Speeds
Slower (up to 600 MB/s)
Faster (typically 3000 MB/s and up to 7,500 MB/s)
Latency
Higher
Lower
Scalability
Limited
Scalable
What Are M.2 Drives?
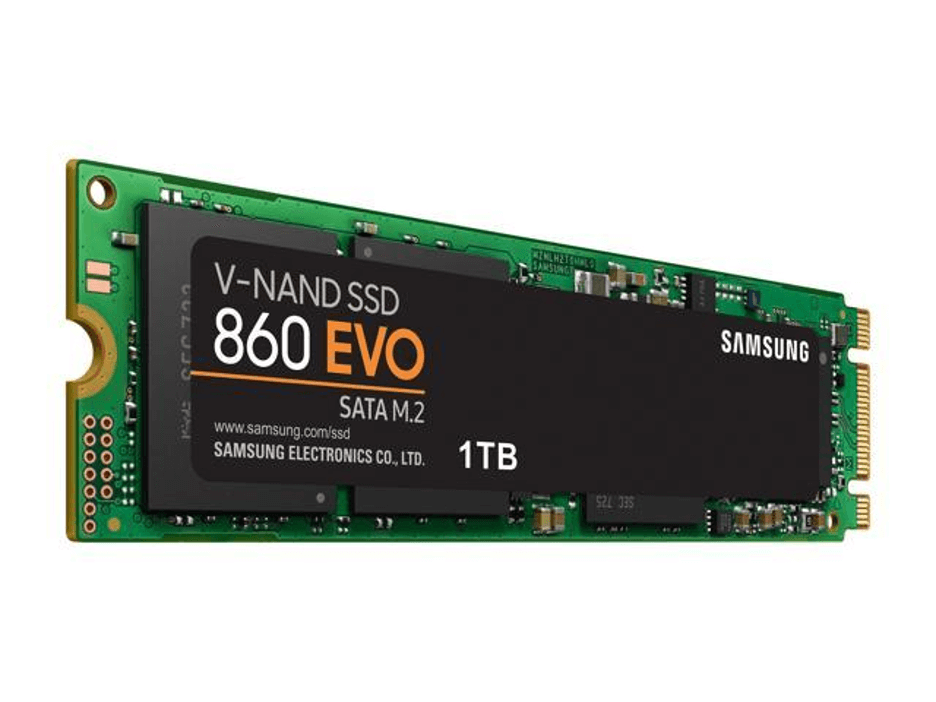
M.2 drives, also known as Next Generation Form Factor (NGFF) drives, are a type of SSD that uses the M.2 interface to connect directly into a computer’s motherboard without the need for cables. M.2 is a form factor, which refers to the standard size of a component. So, while we’re comparing NVMe to SATA in storage protocol above, a direct comparison for the M.2 SSD is a traditional, 2.5 inch SSD.
M.2 SSDs are significantly smaller than traditional, 2.5 inch SSDs. Because they can use either SATA or NVMe to connect to the motherboard, they have the potential to be much faster when they’re utilizing the latter. They’re also more power-efficient than other types of SSDs, which improves battery life in portable devices. Because they take up less space while delivering all of the above, M.2 drives have become popular in gaming setups. (Game on, friends.)
Even at this smaller size, M.2 SSDs are able to hold as much data as other SSDs, ranging up to 8TB in storage size. But, while they can hold just as much data and are generally faster than other SSDs, they also come at a higher cost. As the old adage goes, you can only have two of the following things: cheap, fast, or good.
M.2 drives are easy to install, and they can be added to most modern motherboards that have an M.2 slot. If your motherboard does not have an M.2 slot, you may be able to use an M.2 drive by using an adapter card that fits into a PCIe slot. So, before you run out and buy an M.2 SSD, you’ll need to know which interface your computer will accept, M.2 SATA or M.2 PCIe.
What Are mSATA Drives?
mSATA, or mini-SATA, is basically a smaller version of the full-size SATA SSD that is designed for smaller form factor systems where space is limited. The mSATA form factor is compact like M.2, but they are not interchangeable. Currently, mSATA drives only support the SATA interface.
What Are U.2 Drives?
U.2 drives look like a 2.5” drive but are a bit thicker, and they use a different connector that sends data through a PCIe interface. The U.2 SSD was developed to enable the newer and faster NVMe-based PCIe SSDs to plug into the same drive backplane as older SAS and SATA drives. This allows the drives to be hot-swappable, an especially useful feature in enterprise server and storage systems.
Which SSD Is Best to Use?
There are a few factors to consider in choosing which drive is best for you. As you compare the different components of your build, consider your technical constraints, budget, capacity needs, and speed priority.
Technical Constraints
Check the capability of your system before choosing a drive, as some older devices don’t have the components needed for NVMe connections. Also, check that you have enough PCIe connections to support multiple PCIe devices. Not enough lanes, or only specific lanes, means you may have to choose a different drive or that only one of your lanes will be able to connect to the NVMe drive at full speed.
The same advice holds if you’re adding an SSD to your NAS array. Most newer models will be compatible with adding an SSD, but you should always double check your NAS specs before you commit to a purchase. And remember: even though SSDs offer many benefits, especially when you’re looking to add caching or using your NAS for media workflows, there are several use cases where you’d see minimal advantage compared with an HDD, such as if you want a NAS to store large amounts of infrequently accessed files (i.e. in backup/archive scenarios).
Budget
If you plan to be making a lot of large file transfers or want to have the highest speeds for gaming, then an NVMe SSD is what you want. Until recently SATA SSDs were much more affordable options compared with NVMe drives, but that is changing rapidly. For example, at the time of publication, a Samsung 1TB SATA SSD (870 EVO) retails for $990 on Amazon, while a Samsung 1TB NVMe drive (970 EVO) is listed for $150only $98 on sale on Amazon. That said, those 8TB NVMe drives we talked about are running about $850+, depending on the manufacturer.
Drive Capacity
SATA drives usually range from 500GB to 16TB in storage capacity. Most M.2 drives top out at 2TB, although some may be available at 4TB and 8TB models at much higher prices.
Drive Speed
When choosing the right drive for your setup, remember that SATA M.2 drives and 2.5 inch SSDs provide the same level of speed, so to gain a performance increase, you will have to opt for the NVMe-connected drives. While NVMe SSDs are going to be much faster than SATA drives, you may also need to upgrade your processor to keep up or you may experience worse performance. Finally, remember to check read and write speeds on a drive as some earlier generations of NVMe drives can have different speeds.
Whatever You Choose, Back It Up
Before choosing a new drive, remember to back up all of your data. Backing up is essential as every drive will eventually fail and need to be replaced. The basis of a solid backup plan requires three copies of your data: one on your device, one backup saved locally, and one stored off-site. Storing a copy of your data in the cloud ensures that you’re able to retrieve it if any data loss occurs on your device.
Interested in learning more about other drive types or best ways to optimize your setup? Let us know in the comments below.
FAQs about NVMe vs. M.2 drives
What is the difference between NVMe and M.2 drives?
NVMe and M.2 are often used interchangeably, but they refer to different aspects of storage technology. Non-Volatile Memory Express (NVMe) drives attach to the Peripheral Component Interconnect Express (PCIe) slot directly on a motherboard instead of using the traditional SATA interface, resulting in higher data transfer speeds. M.2, on the other hand, is a physical form factor or connector used for SSDs. M.2 drives can support various storage interfaces, including NVMe, SATA, and others, providing flexibility in terms of compatibility and speed.
Which is faster, NVMe or M.2 drives?
NVMe and M.2 drives are not directly comparable in terms of speed because they refer to different aspects of storage technology. NVMe (Non-Volatile Memory Express) is a storage protocol that provides high-speed communication between the computer’s CPU and SSDs. It is designed to take full advantage of the capabilities of SSDs and can offer significantly faster data transfer speeds compared to traditional interfaces like SATA.
M.2, on the other hand, refers to a physical form factor or connector used for storage devices, including SSDs. M.2 drives can support various interfaces, including NVMe, SATA, and others. The speed of an M.2 drive depends on the specific interface it uses. NVMe M.2 drives, which utilize the NVMe protocol, can provide faster speeds compared to M.2 drives that use the SATA interface.
In summary, NVMe is a storage protocol that can be implemented in various form factors, including M.2, and NVMe drives tend to offer faster speeds compared to M.2 drives that utilize the SATA interface.
Can NVMe be used in any M.2 slot?
NVMe drives can generally be used in M.2 slots, but it is important to ensure compatibility with the specific M.2 slot on your motherboard. M.2 slots can support different types of interfaces, including SATA and NVMe.
What are the advantages of NVMe in M.2 drives?
NVMe (Non-Volatile Memory Express) is a storage protocol that can be implemented through various form factors, one of which is M.2.
The main advantage of NVMe technology is its high-speed data transfer capabilities. Compared to traditional storage interfaces like SATA, NVMe provides significantly faster performance. It leverages the Peripheral Component Interconnect Express (PCIe) interface, allowing for direct communication between the CPU and the SSD. This results in reduced latency and improved overall system responsiveness.
M.2, on the other hand, is a physical form factor or connector that can support various interfaces, including SATA and NVMe. M.2 drives can accommodate NVMe SSDs, allowing them to take advantage of the faster speeds provided by the NVMe protocol. In addition to the ability to utilize a faster NVMe protocol, the advantages of an M.2 size are its small size and easy direct-to-motherboard installation.
Are NVMe drives more expensive than SATA drives?
Until recently SATA SSDs were much more affordable options compared with NVMe drives, but that is changing rapidly. For example, as of June 2023, a Samsung 1TB SATA SSD (870 EVO) retails for $90 on Amazon, while a Samsung 1TB NVMe drive (970 EVO) is listed for only $98 on sale on Amazon. Prices are now comparable.
Cloud technology has revolutionized IT operations over the past decade and a half. According to the Flexera 2024 State of the Cloud Report, 89% of respondents reported having a multi-cloud strategy in 2024, up slightly from 87% in 2023. Businesses are steadily relying on multi-cloud environments to enhance flexibility, optimize costs, and keep up with hardware improvements.
A multi-cloud approach leverages the strengths of multiple cloud providers to meet diverse business needs. Rather than relying on a single cloud provider or on-premises infrastructure, organizations distribute workloads across various platforms.
For those not yet utilizing a multi-cloud strategy or seeking to maximize their current approach, this guide explains the essentials of multi-cloud architecture. It covers the benefits of a multi-cloud environment, how to implement it effectively, and critical considerations to keep in mind for a successful deployment.
First, some multi-cloud history
The shift to multi-cloud infrastructure over the past decade and a half can be traced to two trends in the cloud computing landscape. First, AWS, Google, and Microsoft—otherwise known as the “Big Three” and sometimes called hyperscalers—are no longer the only options for IT departments looking to move to the cloud. Since AWS launched in 2006, specialized infrastructure as a service (IaaS) providers, such as CoreWeave, DigitalOcean, and, well, us, have emerged to challenge the Big Three, giving companies more options for cloud deployments. Many challengers focus on specialized cloud functions—CoreWeave, for example, is a primarily GPU provider, though it also has its own storage cloud—who enhance their core functionality with partnerships. (What we like to call the open cloud.)
Second, many companies spent the decade after AWS’s launch making the transition from on-premises to the cloud, and dealing with complicated and expensive hyperscaler pricing structures that were the only option at the time. Now, new companies are built to be cloud native and existing companies are poised to optimize their cloud deployments. They’ve crossed the hurdle of moving or connecting on-premises infrastructure to the cloud and can focus on how to architect their cloud environments to maximize the advantages of multi-cloud.
What is multi-cloud?
Nearly every software as a service (SaaS) platform is hosted in the cloud. So, if your company uses a tool like Microsoft 365 for Business or Google Workspace along with any other cloud service or platform, you’re technically operating in a multi-cloud environment. But, using more than one SaaS platform does not constitute a true multi-cloud strategy.
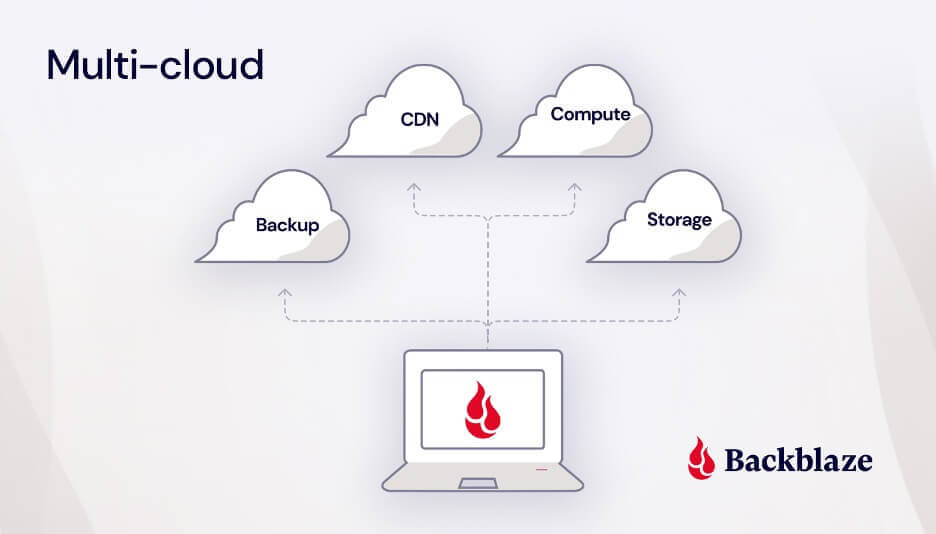
In the cloud services industry, when we talk about “multi-cloud,” we’re referring to the use of multiple public cloud platforms to build your company’s infrastructure. This includes all aspects of your tech stack such as storage, networking, computing power, and more.
Essentially, it means not putting all your eggs in one basket (or in one cloud provider like AWS, Google, or even on-premises infrastructure), but instead leveraging the strengths of different cloud providers to meet your specific needs.
Multi-cloud vs. hybrid cloud: what’s the diff?
To be more precise, multi-cloud refers to the use of more than one public cloud platform. This strategy allows businesses to leverage the unique strengths and services of different providers, optimizing for performance and cost.
On the other hand, a hybrid cloud combines a private cloud with a public cloud. A private cloud is typically hosted on-premises, but it can also be hosted in a colocation data center. The key difference between private and public clouds is that a private cloud’s infrastructure, hardware, and software are maintained and used exclusively by your business.
Things can get even more interesting when a company uses a private cloud along with multiple public clouds. This approach, known as a hybrid multi-cloud strategy, maximizes flexibility and resilience, though it can be complex to manage.
Did you know?
The International Data Corporation (IDC) is forecasting cloud infrastructure spending to jump to $129.9 billion in 2024. That’s up almost 20% compared to 2023.
How to implement multi-cloud: use cases
As multi-cloud deployments have become integral to operations, IT teams have incorporated them into an overall enterprise cloud strategy. And, as multi-cloud infrastructure has become more common, leading tools like Veeam, Commvault, Kubernetes, iconik, and rclone have been built to integrate with specific storage targets and complex storage infrastructure.
So, how do you actually use a multi-cloud strategy, and what is a multi-cloud strategy good for? Multi-cloud has a number of compelling use cases and rationales, including:
Disaster recovery
Failover
Cost optimization
Avoiding vendor lock-in
Data sovereignty
Access to specialized services
Disaster recovery
One of the key advantages of a multi-cloud environment is enhanced disaster recovery through redundancy. By leveraging multiple cloud providers, IT departments can easily implement the modern 3-2-1 backup strategy: three copies of data, stored on two different types of media, with one copy stored off-site or in the cloud. As cloud services have advanced, the primacy of on-premises backups has diminished, with data recovery from the cloud now almost as fast as from on-premises infrastructure and protected by regional separation in case of natural disaster.
Failover
Similarly, some cloud-native companies utilize multiple cloud providers to host mirrored copies of their active production data. If one of their public clouds suffers an outage, they have mechanisms in place to direct their applications to failover to a second public cloud.
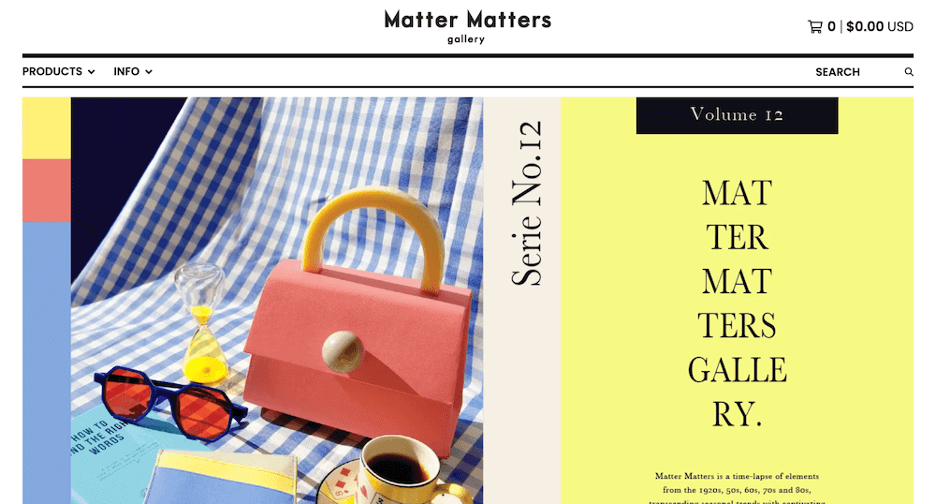
E-commerce company, Big Cartel, pursued this strategy after AWS suffered a number of outages in past years that gave Big Cartel cause for concern. They host more than one million websites on behalf of their clients, and an outage would take them all down. “Having a single storage provider was a single point of failure that we grew less and less comfortable with over time,” Big Cartel Technical Director, Lee Jensen, acknowledged. Now, their data is stored in two public clouds—Amazon S3 and Backblaze B2 Cloud Storage. Their content delivery network (CDN), Fastly, preferentially pulls data from Backblaze B2 with Amazon S3 as failover.
Matter Matters: A Big Cartel customer site.
Cost optimization
Challenger companies can offer incentives that compete with the Big Three and pricing structures that suit specialized data use cases. For example, some cloud providers offer free egress but put limits on how much data can be downloaded, while others charge nominal egress fees, but don’t cap downloads. Or, you might see things like minimum storage duration fees, which means that you get charged for your data being stored even after deletion. Savvy companies employ multiple clouds for different types of data depending on how much data they have and how often it needs to be accessed.
simmer.io, a community site that makes sharing Unity WebGL games easy for indie game developers, would get hit with egress spikes from Amazon S3 whenever one of their hosted games went viral. The fees turned their success into a growth inhibitor. simmer.io mirrored their data to Backblaze B2 Cloud Storage and reduced egress to $0 as a result of the partnership between Backblaze and Cloudflare. They can grow their site without having to worry about increasing egress costs over time or usage spikes when games go viral, and they doubled redundancy in the process.
Dragon Spirit: A simmer.io hosted game.
Avoiding vendor lock-in
Many companies initially adopted one of the Big Three because they were the only game in town, but later felt restricted by their closed systems. Companies like Amazon and Google don’t play nice with each other and both seek to lock customers in with proprietary services. Adopting a multi-cloud infrastructure with interoperable providers gives these companies more negotiating power and control over their cloud deployments.
For example, Gideo, a connected TV app platform, initially used an all-in-one cloud provider for compute, storage, and content delivery, but felt they had no leverage to reduce their bills or improve the service they were receiving. They adopted a multi-cloud approach, building a tech stack with a mix of unconflicted partners where they no longer feel beholden to one provider.
Data sovereignty
Many countries, including those in the European Union (EU), have enacted stringent laws regulating where and how data can be stored, often referred to as data sovereignty or data residency requirements. These regulations ensure that sensitive data remains within specific geographical boundaries to protect privacy and maintain national security.
For companies subject to these data residency standards, employing a multi-cloud approach is a strategic way to meet regulatory requirements. By using multiple public cloud providers with diverse geographic footprints, organizations can store data in the required regions. This approach not only ensures compliance with local laws but also enhances data security and accessibility.
Access to specialized services
Organizations may use different cloud providers to access specialized or complimentary services. For example, a company may use a public cloud like DigitalOcean or Vultr for access to compute resources or bare metal servers, but store their data with a different, interoperable public cloud that specializes in storage (aka Backblaze!). Or, a company may use a cloud storage provider in combination with a cloud CDN to distribute content faster to end users.
The advantages of multi-cloud infrastructure
No matter the use case or rationale, companies achieve a number of advantages from deploying a multi-cloud infrastructure, including:
Better reliability and lower latency: In a failover scenario, if one cloud goes down, companies with a multi-cloud strategy have others to fall back on. If a company uses multiple clouds for data sovereignty or in combination with a CDN, they see reduced latency as their clouds are located closer to end users.
Redundancy: With data in multiple, isolated clouds, companies are better protected from threats. If cybercriminals are able to access one set of data, companies are more likely to recover if they can restore from a second cloud environment that operates on a separate network.
More freedom and flexibility: With a multi-cloud system, if something’s not working or if costs start to become unmanageable, companies have more leverage to influence changes and the ability to leave if another vendor offers better features or more affordable pricing. Businesses can also take advantage of industry partnerships to build flexible, cloud-agnostic tech stacks using best-of-breed providers.
Affordability: It may seem counterintuitive that using more clouds would cost less, but it’s true. Diversified cloud providers like AWS make their services hard to quit for a reason—when you can’t leave, they can charge you whatever they want. A multi-cloud system allows you to take advantage of competitive pricing among platforms.
Best-of-breed services: Adopting a multi-cloud strategy means you can work with providers who specialize in doing one thing really well, rather than trying to be everything to everyone. Cloud platforms specialize to offer customers top-of-the-line service, features, and support rather than providing a one-size-fits all solution.
The challenges of multi-cloud infrastructure
The advantages of a multi-cloud system have attracted an increasing number of companies, but it’s not without challenges. According to a 2024 IDC Tracker, managing costs is complex due to different pricing models and billing structures across cloud providers, necessitating real-time cost monitoring and predictive analytics from any cloud integration. Additionally, Gartner highlights the shortage of skilled professionals to manage multi-cloud environments, requiring continuous upskilling and training investments. Basically, a good IT team is worth its weight in… cloud storage savings.
Despite these challenges plus performance management, security concerns, compliance requirements, and others, multi-cloud strategies offer improved flexibility and resilience, making them a valuable approach for medium to large enterprises.
Overcome multi-cloud challenges with multi-cloud best practices.
Multi-cloud best practices
As you plan your multi-cloud strategy, keep the following considerations in mind:
Deployment strategies
Cost management
Data security
Governance
Multi-cloud deployment strategies
There are likely as many ways to deploy a multi-cloud strategy as there are companies using a multi-cloud strategy. But, they generally fall into two broader categories—redundant or distributed.
In a redundant deployment, data is mirrored in more than one cloud environment, for example, for failover or disaster recovery. Companies that use a multi-cloud approach rather than a hybrid approach to store backup data are using a redundant multi-cloud deployment strategy. Most IT teams looking to use a multi-cloud approach to back up company data or environments will fall into this category.
A distributed deployment model more often applies to software development teams. In a distributed deployment, different workloads, or different components of the same application are spread across multiple cloud computing environments based on the best fit. For example, a DevOps team might host their compute infrastructure in one public cloud and storage in another.
Your business requirements will dictate which type of deployment you should use. Knowing your deployment approach from the outset can help you pick providers with the right mix of services and billing structures for your multi-cloud strategy.
Multi-cloud cost management
Managing costs in a multi-cloud environment is a challenge that every company faces. Effective cost management requires robust monitoring tools to track cloud utilization and spending, providing visibility into usage and identifying areas for optimization. Choosing cloud providers with straightforward, transparent pricing is essential to avoid unexpected costs and simplify budgeting.
Multi-cloud data security
Security risks increase as your cloud environment becomes more complex. There are more attack targets, and you’ll want to plan security measures accordingly. To take advantage of multi-cloud benefits while reducing risk, follow multi-cloud security best practices:
Ensure you have controls in place for authentication across platforms. Your different cloud providers likely have different authentication protocols, and you need a framework and security protocols that work across providers. Hint: Use a password management tool or a single-sign on (SSO) login methods.
Train your team appropriately to identify cybersecurity risks.
Stay up-to-date on security patches. Each cloud provider will publish their own upgrades and patches. Make sure to automate upgrades as much as possible.
Consider using a tool like Object Lock to protect backups with immutability. Object Lock allows you to store objects using a write once, read many (WORM) model, meaning after it’s written, data cannot be modified or deleted for a defined period of time. Any attempts to manipulate, copy, encrypt, change, or delete the file will fail during that time. The files may be accessed, but no one can change them, including the file owner or whoever set the Object Lock.
Multi-cloud governance
As cloud adoption grows across your company, you’ll need to have clear protocols for how your infrastructure is managed. Consider creating standard operating procedures for cloud platform management and provisioning to avoid shadow IT proliferation, where teams may adopt tools (in the cloud or not) that IT has not approved and isn’t managing. And, set up policies for centralized security monitoring.
Ready for multi-cloud? Here are some migration strategies
If you’re ready to go multi-cloud, you’re probably wondering how to get your data from your on-premises infrastructure to the cloud or from one cloud to another. After choosing a provider that fits your needs, you can start planning your data migration. There are a range of tools for moving your data, but when it comes to moving between cloud services, a tool like our Universal Data Migration can help make things a lot easier and faster.
How Backblaze fits into a multi-cloud strategy
Backblaze B2 enhances versatile and secure backup solutions with features like Object Lock for immutable data storage and 3x free egress for when you need to recover data. In partnership with backup solutions like Veeam and disaster recovery services like Cloud Instant Backup Recovery, businesses can utilize Backblaze in a multi-cloud architecture to ensure continuous operation during ransomware attacks, hardware failures, or even force majeure. Backblaze also integrates into your multi-cloud tech stack so you can build applications and safeguard datasets on S3 compatible cloud object infrastructure with connected compute and integrated CDNs.
Have any more questions about multi-cloud or cloud migration? Let us know in the comments.
FAQs about multi-cloud architecture guide
What is multi-cloud storage?
Multi-cloud storage is a term for the use of multiple cloud providers within one organization. For example, if your organization uses one cloud storage provider for sensitive medical documents to comply with HIPAA and another cloud storage provider for non-sensitive day-to-day documents, you’re using multi-cloud storage.
What is the difference between multi-cloud and hybrid cloud?
Multi-cloud refers to the process of using multiple clouds within the same cloud storage system. Hybrid cloud, on the other hand, refers to using two different kinds of cloud storage systems—private clouds and public clouds. They are both options that can be incredibly beneficial for many people and organizations, but they’re different methods of approaching cloud storage.
When should I use multi-cloud?
Multi-cloud is a common cloud storage strategy, and most organizations should consider its value for their operations. Multi-cloud has a number of compelling use cases and rationales, including disaster recovery, failover, cost optimization, avoiding vendor lock-in, data sovereignty, and access to specialized services.
What are the benefits of multi-cloud?
Multi-cloud storage strategies offer many benefits depending on how you employ them. They provide more flexibility to meet or exceed regulatory and compliance requirements depending on your industry. They provide greater resilience and protection for your backup and recovery systems. And they provide you with greater flexibility to find the storage solutions that work best for your operations and your budget. Adding cloud providers can increase complexity in billing and administration, but properly managed, it provides your business the ability to better protect and use your data.
This article has been updated since it was originally published in 2021.
When we first published this article, a $70 million ransom demand was unprecedented. Today, demands have reached as high as $240 million, a sum that the Hive ransomware group opened negotiations with in an attack on MediaMarkt, Europe’s largest consumer electronics retailer.
But then, as now, the ransoms themselves are just a portion, and often a small portion, of the overall cost of ransomware. Ransomware attacks are crimes of opportunity, and there’s a lot more opportunity in the mid-market, where the odd $1 million demand doesn’t make headlines and the victims are less likely to be adequately prepared to recover. And, the cost of those recoveries is what we’ll get into today.
In this post, we’re breaking down the true cost of ransomware and the drivers of those costs.
Read More About Ransomware
This post is a part of our ongoing series on ransomware. Take a look at our other posts for more information on how businesses can defend themselves against a ransomware attack, important industry trends, and more.
Ransom Payments Are the First Line Item
The Sophos State of Ransomware 2023 report, a survey of 3,000 IT decision makers from mid-sized organizations in 14 countries, found the average ransom payment was $1.54 million. This is almost double the 2022 figure of $812,380, and almost 10 times the 2020 average of $170,404, when we last published this article. Coveware, a security consulting firm, found that the average ransom payment for Q2 2023 was $740,144, also representing a big spike over previous quarters. While the specific numbers vary depending on sampling, both reports point to ransoms going up and up.
Sophos found that the mean recovery cost excluding the ransom payment was $2.6 million when the targeted organization paid the ransom and got their data back. And, that cost was still $1.6 million when businesses used backups to restore data.
The cost of recovery comes from a wide range of factors, including:
Downtime.
People hours.
Investment in stronger cybersecurity protections.
Repeat attacks.
Higher insurance premiums.
Legal defense and settlements.
Lost reputation.
Lost business.
Downtime
When a company’s systems and data are compromised and operations come to a halt, the consequences are felt across the organization. Financially, downtime results in immediate revenue loss. And, productivity takes a significant hit as employees are unable to access critical resources, leading to missed deadlines and disrupted workflows. According to Coveware, the average downtime in Q2 2022 (the last quarter they collected data on downtime) amounted to over three weeks (24 days). And according to Sophos, 53% of survey respondents took more than one month to recover from the attack. This time should be factored in when calculating the true cost of ransomware.
People Hours
In the aftermath of a ransomware attack, a significant portion, if not all, of a company’s resources will be channeled towards the recovery process. The IT department will be at the forefront, working around the clock to restore systems to full functionality. The marketing and communications teams will shoulder the responsibility of managing crisis communications, while the finance team may find themselves in negotiations with the ransomware perpetrators. Meanwhile, human resources will be addressing employee inquiries and concerns stemming from the incident. Calculating the total hours spent on recovery may not be possible, but it’s a factor to consider in planning.
After recovery, the long term effects of a cybersecurity breach can still be felt in the workforce. In a study of the mental health impacts of cybersecurity on employees, Northwave found that physical and mental health symptoms were still existent up to a year after the cybersecurity attack, and affected both employee morale and business goals.
Investment in Stronger Cybersecurity Protections
It is highly probable that a company will allocate a greater portion of its budget towards bolstering its cybersecurity measures after being attacked by ransomware, and rightfully so. It’s a prudent and necessary response. As attacks continue to increase in frequency, cyber insurance providers will continue to tighten requirements for coverage. In order to maintain coverage, companies will need to bring systems up to speed.
Repeat Attacks
One of the cruel realities of being attacked by ransomware is that it makes businesses a target for repeat attacks. Unsurprisingly, cybercriminals don’t always keep their promises when companies pay ransoms. In fact, paying ransoms lets cybercriminals know you’re an easy future mark. They know you’re willing to pay.
Repeat attacks happen when the vulnerability that allowed cybercriminals access to systems remained susceptible to exploitation. Copycat ransomware operators can easily exploit vulnerabilities that go unaddressed even for a few days.
Higher Insurance Premiums
As more and more companies file claims for ransomware attacks and recoveries and ransom demands continue to increase, insurers are upping their premiums. In essence, insurers have been confronted with the stark reality that the financial toll exacted by ransomware incidents far exceeds what was once anticipated. In response to this growing financial strain, insurance providers are left with little choice but to raise their premiums. This uptick in premiums reflects the increasing risk landscape of the digital age, where the ever-evolving tactics and sophistication of cybercriminals necessitate a recalibration of risk assessment models and pricing structures within the insurance industry.
Legal Defense and Settlements
When attacks affect consumers or customers, victims can expect to hear from the lawyers. After a 2021 ransomware attack, payroll services provider UKG agreed to a $6 million settlement. And, big box stores like Target and Home Depot both paid settlements in the tens of millions of dollars following breaches. Even if your information security practices would hold up in court, for most companies, it’s cheaper to settle than to suffer a protracted legal battle.
Lost Reputation and Lost Business
When ransomware attacks make headlines and draw public attention, they can erode trust among customers, partners, and stakeholders. The perception that a company’s cybersecurity measures were insufficient to protect sensitive data and systems can lead to a loss of credibility. Customers may question the safety of their personal information.
Rebuilding a damaged reputation is a challenging and time-consuming process, requiring transparent communication, proactive security improvements, and a commitment to regaining trust. Ultimately, the impact of reputation loss goes beyond financial losses, as it can significantly affect an organization’s long-term viability and competitiveness in the market.
What You Can Do About It: Defending Against Ransomware
The business of ransomware is booming with no signs of slowing down, and the cost of recovery is enough to put some ill-prepared companies out of business. If it feels like the cost of a ransomware recovery is out of reach, that’s all the more reason to invest in harder security protocols and disaster recovery planning sooner rather than later.
For more information on the ransomware economy, the threat small to mid-sized businesses (SMBs) are facing, and steps you can take to protect your business, download The Complete Guide to Ransomware.
Cost of Ransomware FAQs
1. What is the highest ransomware ransom ever demanded?
Today, ransom demands have reached as high as $240 million, a sum demanded by the Hive ransomware group in an attack on MediaMarkt, Europe’s largest consumer electronics retailer.
2. What is the average ransom payment in 2023?
Average ransom payments vary depending on how reporting entities sample data. Some estimates put the average ransom payment in 2023 in the hundreds of thousands of dollars up to over half a million dollars.
3. How much does ransomware recovery cost?
Ransomware recovery can easily cost in the multiple millions of dollars. The cost of recovery comes from a wide range of factors, including downtime, people hours, investment in stronger cybersecurity protections, repeat attacks, higher insurance premiums, legal defense, lost reputation, and lost business.
4. How long does ransomware recovery take?
When a company’s systems and data are compromised, and operations come to a halt, the consequences are felt across the organization. Ransomware recovery can take anywhere from a few days, if you’re well prepared, or up to six months or longer.
Ransomware continues to proliferate for a simple reason—it’s profitable. And it’s profitable not just for the ransomware developers themselves—they’re just one part of the equation—but for a whole ecosystem of players who make up the ransomware economy. To understand the threats to small and medium-sized businesses (SMBs) and organizations today, it’s important to understand the scope and scale of what you’re up against.
Today, we’re digging into how the ransomware economy operates, including the broader ecosystem and the players involved, emerging threats to SMBs, and the overall financial footprint of ransomware worldwide.
This post is a part of our ongoing series on ransomware. Take a look at our other posts for more information on how businesses can defend themselves against a ransomware attack, and more.
Cybercriminals have long been described as operating in “gangs.” The label conjures images of hackers furiously tapping away at glowing workstations in a shadowy warehouse. But the work of the ransomware economy today is more likely to take place in a boardroom than a back alley. Cybercriminals have graduated from gangs to highly complex organized crime syndicates that operate ransomware brands as part of a sophisticated business model.
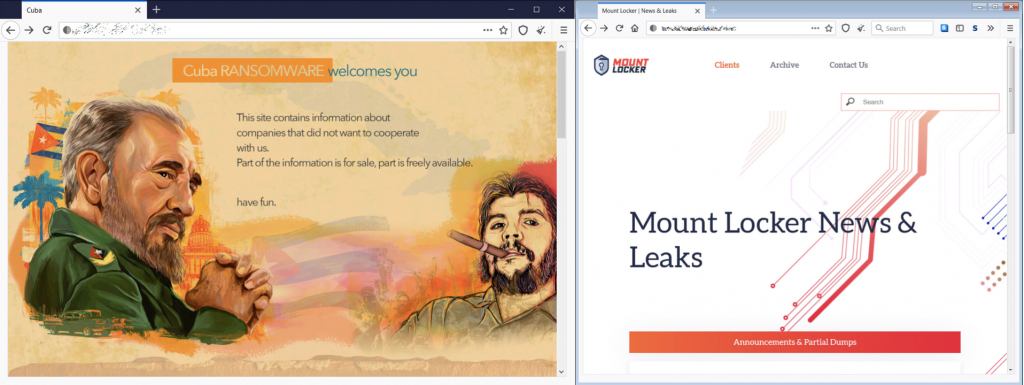
Operators of these syndicates are just as likely to be worrying about user experience and customer service as they are with building malicious code. A look at the branding on display on some syndicates’ leak sites makes the case plain that these groups are more than a collective of expert coders—they’re savvy businesspeople.
Source: Bleepingcomputer.com.
Ransomware operators are often synonymous with the software variant they brand, deploy, and sell. Many have rebranded over the years or splintered into affiliated organizations. Some of the top ransomware brands operating today, along with high profile attacks they have carried out, are shown in the infographic below:
The groups shown above do not constitute an exhaustive list. In June 2021, FBI Director Christopher Wray stated that the FBI was investigating 100 different ransomware variants and new ones pop up everyday. While some brands have existed for years (Ryuk, for example), the list is also likely obsolete as soon as it’s published. Ransomware brands bubble up, go bust, and reorganize, changing with the cybersecurity tides.
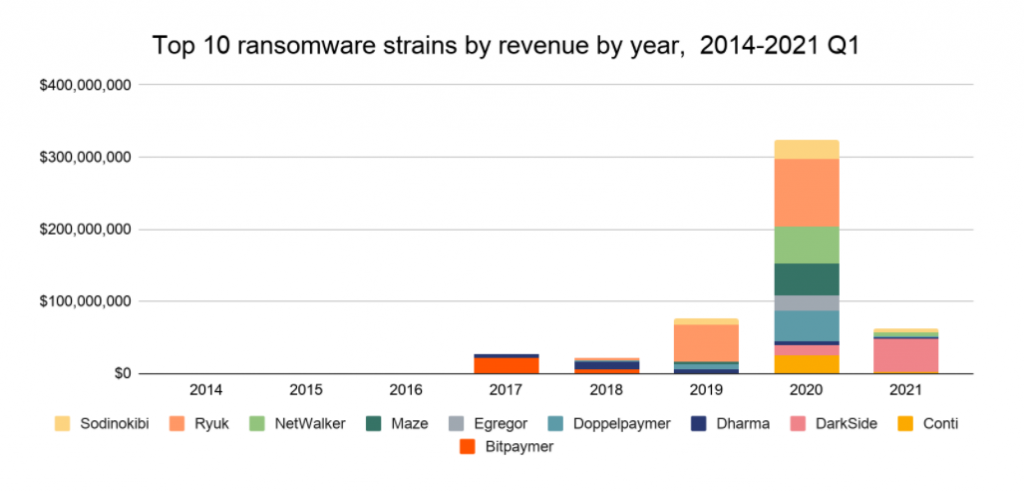
Chainalysis, a blockchain data platform, published their Ransomware 2021: Critical Mid-year Update that shows just how much brands fluctuate year to year and, they note, even month to month:
Ransomware operators may appear to be single entities, but there is a complex ecosystem of suppliers and ancillary providers behind them that exchange services with each other on the dark web. The flowchart below illustrates all the players and how they interact:
Dark Web Service Providers
Cybercrime “gangs” could once be tracked down and caught like the David Levi Phishing Gang that was investigated and prosecuted in 2005. Today’s decentralized ecosystem, however, makes going after ransomware operators all the more difficult. These independent entities may never interact with each other outside of the dark web where they exchange services for cryptocurrency:
Botmasters: Create networks of infected computers and sell access to those compromised devices to threat actors.
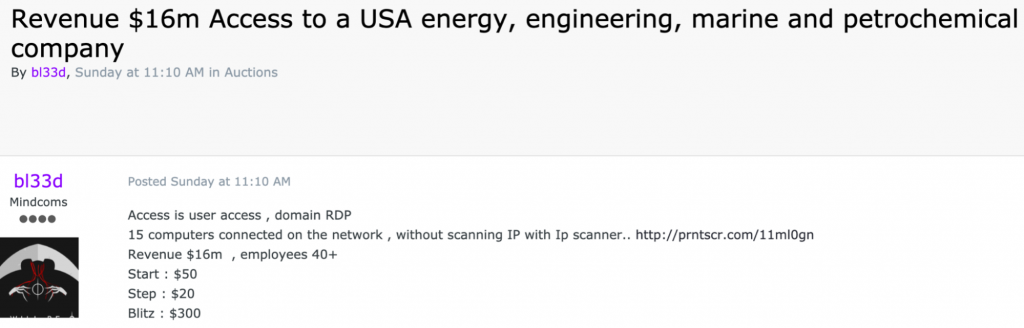
Access Sellers: Take advantage of publicly disclosed vulnerabilities to infect servers before the vulnerabilities are remedied, then advertise and sell that access to threat actors.
Advertisement from an access seller for access to an organization’s RDP. Source: Threatpost.
Operators: The entity that actually carries out the attack with access purchased from botmasters or access sellers and software purchased from developers or developed in-house. May employ a full staff, including customer service, IT support, marketing, etc. depending on how sophisticated the syndicate is.
Developers: Write the ransomware software and sell it to threat actors for a cut of the ransom.
Packer Developers: Add protection layers to the software, making it harder to detect.
Analysts: Evaluate the victim’s financial health to advise on ransom amounts that they’re most likely to pay.
Affiliates: Purchase ransomware as a service from operators/developers who get a cut of the ransom.
Negotiating Agents: Handle interactions with victims.
Laundering Services: Exchange cryptocurrency for fiat currency on exchanges or otherwise transform ransom payments into usable assets.
Victim-side Service Providers
Beyond the collection of entities directly involved in the deployment of ransomware, the broader ecosystem includes other players on the victim’s side, who, for better or worse, stand to profit off of ransomware attacks. These include:
Incident response firms: Consultants who assist victims in response and recovery.
Ransomware brokers: Brought in to negotiate and handle payment on behalf of the victim and act as intermediaries between the victim and operators.
Insurance providers: Cover victims’ damages in the event of an attack.
Legal counsel: Often manage the relationship between the broker, insurance provider, and victim, and advise on ransom payment decision-making.
Are Victim-side Providers Complicit?
While these providers work on behalf of victims, they also perpetuate the cycle of ransomware. For example, insurance providers that cover businesses in the event of a ransomware attack often advise their customers to pay the ransom if they think it will minimize downtime as the cost of extended downtime can far exceed the cost of a ransom payment. This becomes problematic for a few reasons:
First, paying the ransom incentivizes cybercriminals to continue plying their trade.
Second, as Colonial Pipeline discovered, the decryption tools provided by cybercriminals in exchange for ransom payments aren’t to be trusted. More than a month after Colonial paid the $4.4 million ransom and received a decryption tool from the hackers, CEO Joseph Blount testified before Congress that recovery from the attack was still not complete. After all that, they had to rely on recovering from their backups anyway.
The Emergence of Ransomware as a Service
In the ransomware economy, operators and their affiliates are the threat actors that carry out attacks. This affiliate model where operators sell ransomware as a service (RaaS) represents one of the biggest threats to SMBs and organizations today.
Cybercrime syndicates realized they could essentially license and sell their tech to affiliates who then carry out their own misdeeds empowered by another criminal’s software. The syndicates, affiliates, and other entities each take a portion of the ransom.
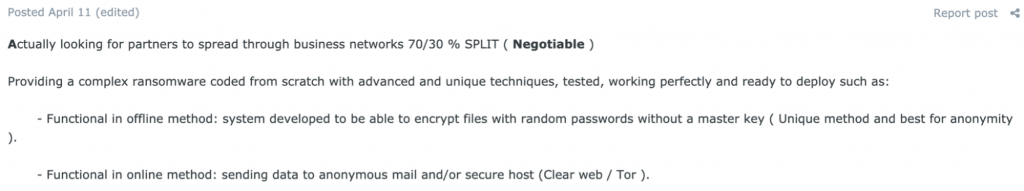
Operators advertise these partner programs on the dark web and thoroughly vet affiliates before bringing them on to filter out law enforcement posing as low-level criminals. One advertisement by the REvil syndicate noted, “No doubt, in the FBI and other special services, there are people who speak Russian perfectly, but their level is certainly not the one native speakers have. Check these people by asking them questions about the history of Ukraine, Belarus, Kazakhstan or Russia, which cannot be googled. Authentic proverbs, expressions, etc.”
Advertisement for ransomware affiliates. Source: Kaspersky.
Though less sophisticated than some of the more notorious viruses, these “as a service” variants enable even amateur cybercriminals to carry out attacks. And they’re likely to carry those attacks out on the easiest prey—small businesses who don’t have the resources to implement adequate protections or weather extended downtime.
Hoping to increase their chances of being paid, low-level threat actors using RaaS typically demanded smaller ransoms, under $100,000, but that trend is changing. Coveware reported in August 2020 that affiliates are getting bolder in their demands. They reported the first six-figure payments to the Dharma ransomware group, an affiliate syndicate, in Q2 2020.
The one advantage savvy business owners have when it comes to RaaS: attacks are high volume (carried out against many thousands of targets) but low quality and easily identifiable by the time they are widely distributed. By staying on top of antivirus protections and detection, business owners can increase their chances of catching the attacks before it’s too late.
The Financial Side of the Ransomware Economy
So, how much money do ransomware crime syndicates actually make? The short answer is that it’s difficult to know because so many ransomware attacks go unreported. To get some idea of the size of the ransomware economy, analysts have to do some sleuthing.
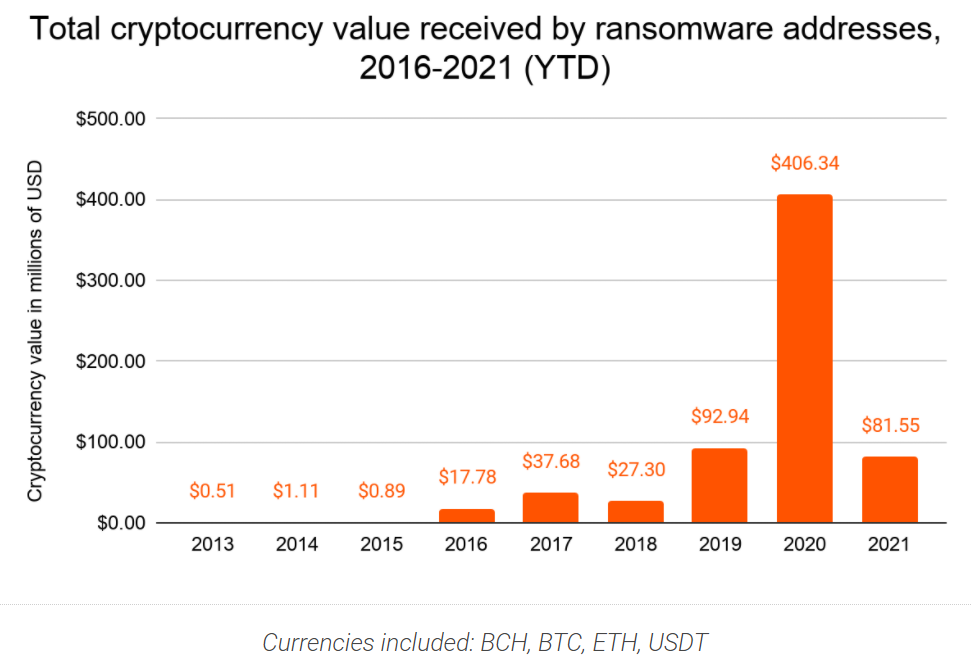
Chainalysis tracks transactions to blockchain addresses linked to ransomware attacks in order to capture the size of ransomware revenues. In their regular reporting on the cybercrime cryptocurrency landscape, they showed that the total amount paid by ransomware victims increased by 311% in 2020 to reach nearly $350 million worth of cryptocurrency. In May, they published an update after identifying new ransomware addresses that put the number over $406 million. They expect the number will only continue to grow.
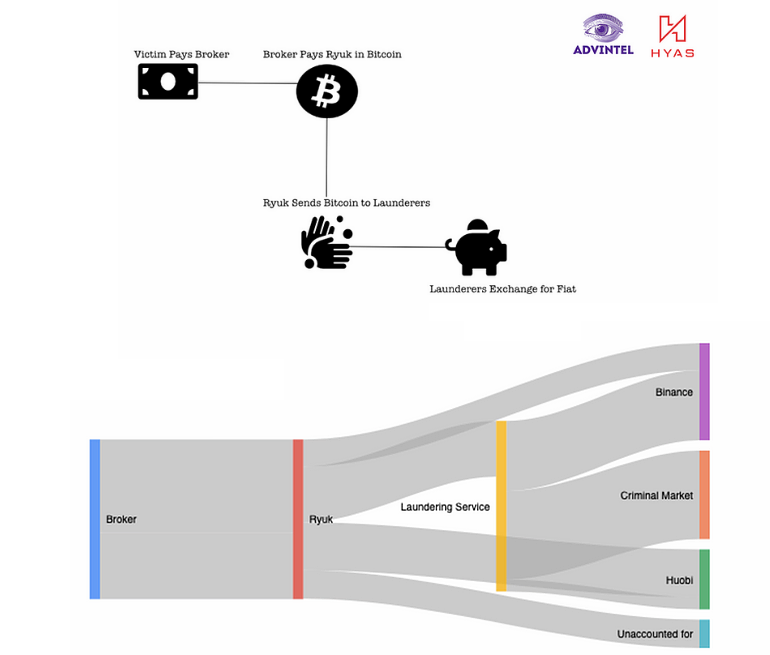
Similarly, threat intel company, Advanced Intelligence, and cybersecurity firm, HYAS, tracked Bitcoin transactions to 61 addresses associated with the Ryuk syndicate. They estimate that the operator may be worth upwards of $150 million alone. Their analysis sheds some light on how ransomware operators turn their exploits and the ransoms paid into usable cash.
Extorted funds are gathered in holding accounts, passed to money laundering services, then either funneled back into the criminal market and used to pay for other criminal services or cashed out at real cryptocurrency exchanges. The process follows these steps, as illustrated below:
The victim pays a broker.
The broker converts the cash into cryptocurrency.
The broker pays the ransomware operator in cryptocurrency.
The ransomware operator sends the cryptocurrency to a laundering service.
The laundering service exchanges the coins for fiat currency on cryptocurrency exchanges like Binance and Huobi.
In an interesting development, the report found that Ryuk actually bypassed laundering services and cashed out some of their own cryptocurrency directly on exchanges using stolen identities—a brash move for any organized crime operation.
Protecting Your Company From Ransomware
Even though the ransomware economy is ever-changing, having an awareness of where attacks come and the threats you’re facing can prepare you if you ever face one yourself. To summarize:
Ransomware operators may seem to be single entities, but there’s a broad ecosystem of players behind them that trade services on the dark web.
Ransomware operators are sophisticated business entities.
RaaS enables even low-level criminals to get in the game.
Ransomware operators raked in at least $406 million in 2020, and likely more than that, as many ransomware attacks and payments go unreported.
We put this post together not to trade in fear, but to prepare SMBs and organizations with information in the fight against ransomware. And, you don’t have to fight it alone. Download our Complete Guide to Ransomware E-book and Guide for even more intel on ransomware today, plus steps to take to defend against ransomware, and how to respond if you do fall victim to an attack.
The old saying, “birds of a feather flock together,” couldn’t be more true of the latest addition to the Backblaze partner network. Today, we announce a new partnership with Vultr—the largest privately-owned, global hyperscale cloud—to serve developers and businesses with infrastructure as a service that’s easier to use and lower cost than perhaps better known alternatives.
With the Backblaze + Vultr combination, developers now have the ability to connect data stored in Backblaze B2 with virtualized cloud compute and bare metal resources in Vultr—providing a compelling alternative to Amazon S3 and EC2. Each Vultr compute instance includes a fixed amount of bandwidth, meaning that developers can easily transfer data between Vultr’s 17 global locations and Backblaze at no additional cost.
In addition to replacing AWS EC2, Vultr’s complete product line also offers load balancers and block storage which can seamlessly replace Amazon Elastic Load Balancing (ELB) and Elastic Block Storage (EBS).
With this partnership, developers of any size can avoid vendor lock-in, access best of breed services, and do more with the data they have stored in the cloud with ease, including:
Running analysis on stored data.
Deploying applications and storing application data.
Transcoding media and provisioning origin storage for streaming and video on-demand applications.
Backblaze + Vultr: Better Together
Vultr’s ease of use and comparatively low costs have motivated more than 1.3 million developers around the world to use its service. We recognized a shared culture in Vultr, which is why we’re looking forward to seeing what our joint customers can do with this partnership. Like Backblaze, Vultr was founded with minimal outside investment. Both services are transparent, affordable, simple to start without having to talk to sales (although sales support is only a call or email away), and, above all, easy. Vultr is on a mission to simplify deployment of cloud infrastructure, and Backblaze is on a mission to simplify cloud storage.
Rather than trying to be everything for everyone, both businesses play to their strengths, and customers get the benefit of working with unconflicted partners.
Vultr’s pricing often comes in at half the cost of the big three—Amazon, Google, and Microsoft—and with Vultr’s bundled egress, we’re working together to alleviate the burden of bandwidth costs, which can be disproportionately huge for small and medium-sized businesses.
“The Backblaze-Vultr partnership means more developers can build the flexible tech stacks they want to build, without having to make needlessly tough choices between access and affordability,” said Shane Zide, VP of Global Partnerships at Vultr. “When two companies who focus on ease of use and price performance work together, the whole is greater than the sum of the parts.”
Fly Higher With Backblaze B2 + Vultr
Existing Backblaze B2 customers now have unfettered access to compute resources with Vultr, and Vultr customers can connect to astonishingly easy cloud storage with Backblaze B2. If you’re not yet a B2 Cloud Storage customer, create an account to get started in minutes. If you’re already a B2 Cloud Storage customer, click here to activate an account with Vultr.
For developers looking to do more with their data, we welcome you to join the flock. Get started with Backblaze B2 and Vultr today.
If you’ve ever wondered how a content delivery network (CDN) works, here’s a decent analogy… For most of the year, I keep one, maybe two boxes of tissues in the house. But, during allergy season, there’s a box in every room. When pollen counts are up, you need zero latency between sneeze and tissue deployment.
Instead of tissues in every room of the house, a CDN has servers in every corner of the globe, and they help reduce latency between a user’s request and when the website loads. If you want to make sure your website loads quickly no matter who accesses it, a CDN can help. Today, we’ll dig into the benefits of CDNs, how they work, and some common use cases with real-world examples.
What Is a CDN?
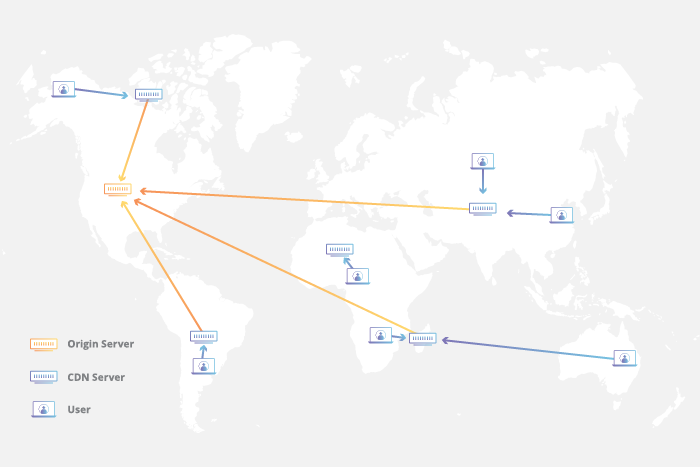
According to Cloudflare, one of the market leaders in CDN services, a CDN is “a geographically distributed group of servers which work together to provide fast delivery of internet content.” A CDN speeds up your website performance by temporarily keeping your website content on servers that are closer to end users. This is known as caching.
When someone in Australia visits your website that’s hosted in New York City, instead of fetching content like images, video, HTML pages, javascript files, etc. all the way from the the “origin store” (the server where the main, original website lives in the Big Apple), the CDN fetches content from an “edge server” that’s geographically closer to the end user at the edge of the network. Your website loads much faster when the content doesn’t have to travel halfway around the world to reach your website visitors.
How Do CDNs Work?
While a CDN does consist of servers that host website content, a CDN cannot serve as a web host itself一you still need traditional web hosting to operate your website. The CDN just holds your website content on servers closer to your end users. It refers back to the main, original website content that’s stored on your origin store in case you make any changes or updates.
Your origin store could be an actual, on-premises server located wherever your business is headquartered, but many growing businesses opt to use cloud storage providers to serve as their origin store. With cloud storage, they can scale up or down as website content grows and only pay for what they need rather than investing in expensive on-premises servers and networking equipment.
The CDN provider sets up their edge servers at internet exchange points, or IXPs. IXPs are points where traffic flows between different internet service providers like a highway interchange so your data can get to end users faster.
Source: Cloudflare.
Not all of your website content will be stored on IXPs all of the time. A user must first request that website content. After the CDN retrieves it from the origin store to whatever server is nearest to the end user, it keeps it on that server as long as the content continues to be requested. The content has a specific “time to live,” or TTL, on the server. The TTL specifies how long the edge server keeps the content. At a certain point, if the content has not been requested within the TTL, the server will stop storing the content.
When a user pulls up website content from the cache on the edge server, it’s known as a cache hit. When the content is not in the cache and must be fetched from the origin store, it’s known as a cache miss. The ratio of hits to misses is known as the cache hit ratio, and it’s an important metric for website owners who use cloud storage as their origin and are trying to optimize their egress fees (the fees cloud storage providers charge to send data out of their systems). The better the cache hit ratio, the less they’ll be charged for egress out of their origin store.
Another important metric for CDN users is round trip time, or RTT. RTT is the time it takes for a request from a user to travel to its destination and back again. RTT metrics help website owners understand the health of a network and the speed of network connections. A CDN’s primary purpose is to reduce RTT as much as possible.
Key Terms: Demystifying Acronym Soup
Origin Store: The main server or cloud storage provider where your website content lives.
CDN: Content delivery network, a geographically distributed group of servers that work to deliver internet content fast.
Edge Server: Servers in a CDN network that are located at the edge of the network.
IXP: Internet exchange point, a point where traffic flows between different internet service providers.
TTL: Time to live, the time content has to live on edge servers.
RTT: Round trip time, the time it takes for a request from a user to travel to its destination and back.
Cache Hit Ratio: The ratio of times content is retrieved from edge servers in the CDN network vs. the times content must be retrieved from the origin store.
Do I Need a CDN?
CDNs are a necessity for companies with a global presence or with particularly complex websites that deliver a lot of content, but you don’t have to be a huge enterprise to benefit from a CDN. You might be surprised to know that more than half of the world’s website content is delivered by CDN, according to Akamai, one of the first providers to offer CDN services.
What Are the Benefits of a CDN?
A CDN offers a few specific benefits for companies, including:
Faster website load times.
Lower bandwidth costs.
Redundancy and scalability during high traffic times.
Improved security.
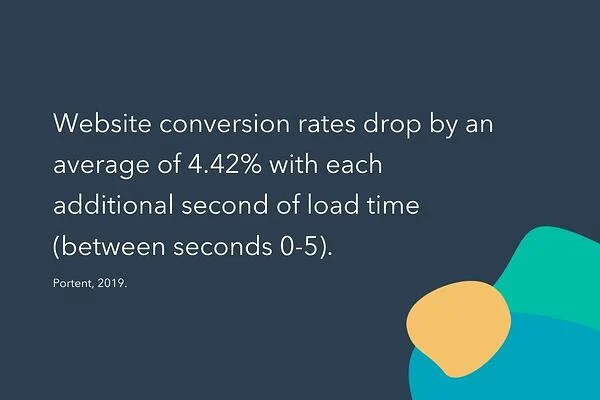
Faster website load times: Content is distributed closer to visitors, which is incredibly important for improving bounce rates. Website visitors are orders of magnitude more likely to click away from a site the longer it takes to load. The probability of a bounce increases 90% as the page load time goes from one second to five on mobile devices, and website conversion rates drop by an average of 4.42% with each additional second of load time. If an e-commerce company makes $50 per conversion and does about $150,000 per month in business, a drop in conversion of 4.42% would equate to a loss of almost $80,000 per year.
If you still think seconds can’t make that much of a difference, think again. Amazon calculated that a page load slowdown of just one second could cost it $1.6 billion in sales each year. With website content distributed closer to website users via a CDN, pages load faster, reducing bounce rates.
Lower bandwidth costs: Bandwidth costs are the costs companies and website owners pay to move their data around telecommunications networks. The farther your data has to go and the faster it needs to get there, the more you’re going to pay in bandwidth costs. The caching that a CDN provides reduces the need for content to travel as far, thus reducing bandwidth costs.
Redundancy and scalability during high traffic times: With multiple servers, a CDN can handle hardware failures better than relying on one origin server alone. If one goes down, another server can pick up the slack. Also, when traffic spikes, a single origin server may not be able to handle the load. Since CDNs are geographically distributed, they spread traffic out over more servers during high traffic times and can handle more traffic than just an origin server.
Improved security: In a DDoS, or distributed denial-of-service attack, malicious actors will try to flood a server or network with traffic to overwhelm it. Most CDNs offer security measures like DDoS mitigation, the ability to block content at the edge, and other enhanced security features.
CDN Cost and Complexity
CDN costs vary by the use case, but getting started can be relatively low or no-cost. Some CDN providers like Cloudflare offer a free tier if you’re just starting a business or for personal or hobby projects, and upgrading to Cloudflare’s Pro tier is just $20 a month for added security features and accelerated mobile load speeds. Other providers, like Fastly, offer a free trial.
Beyond the free tier or trial, pricing for most CDN providers is dynamic. For Amazon CloudFront, for example, you’ll pay different rates for different volumes of data in different regions. It can get complicated quickly, and some CDNs will want to work directly with you on a quote.
At an enterprise scale, understanding if CDN pricing is worth it is a matter of comparing the cost of the CDN to the cost of what you would have paid in egress fees. Some cloud providers and CDNs like those in the Bandwidth Alliance have also teamed up to pass egress savings on to shared users, which can substantially reduce costs related to content storage and delivery. Look into discounts like this when searching for a CDN.
Another way to evaluate if a CDN is right for your business is to look at the opportunity cost of not having one. Using the example above, an e-commerce company that makes $50 per conversion and does $150,000 of business per month stands to lose $80,000 per year due to latency issues. While CDN costs can reach into the thousands per month, the exercise of researching CDN providers and pricing out what your particular spend might be is definitely worth it when you stand to save that much in lost opportunities.
Setting up a CDN is relatively easy. You just need to create an account and connect it to your origin server. Each provider will have documentation to walk you through how to configure their service. Beyond the basic setup, CDNs offer additional features and services like health checks, streaming logs, and security features you can configure to get the most out of your CDN instance. Fastly, for example, allows you to create custom configurations using their Varnish Configuration Language, or VCL. If you’re just starting out, setting up a CDN can be very simple, but if you need or want more bells and whistles, the capabilities are definitely out there.
Who Benefits Most From a CDN?
While a CDN is beneficial for any company with broad geographic reach or a content-heavy site, some specific industries see more benefits from a CDN than others, including e-commerce, streaming media, and gaming.
E-commerce and CDN: Most e-commerce companies also host lots of images and videos to best display their products to customers, so they have lots of content that needs to be delivered. They also stand to lose the most business from slow loading websites, so implementing a CDN is a natural fit for them.
E-commerce Hosting Provider Delivers One Million Websites
Big Cartel is an e-commerce platform that makes it easy for artists, musicians, and independent business owners to build unique online stores. They’ve long used a CDN to make sure they can deliver more than one million websites around the globe at speed on behalf of their customers.
They switched from Amazon’s Cloudfront to Fastly in 2015. As an API-first, edge cloud platform designed for programmability, the team felt Fastly gave Big Cartel more functionality and control than CloudFront. With the Fastly VCL, Big Cartel can detect patterns of abusive behavior, block content at the edge, and optimize images for different browsers on the fly. “Fastly has really been a force multiplier for us. They came into the space with published, open, transparent pricing and the configurability of VCL won us over,” said Lee Jensen, Big Cartel’s Technical Director.
Streaming Media and CDN: Like e-commerce sites, streaming media sites host a lot of content, and need to deliver that content with speed and reliability. Anyone who’s lost service in the middle of a Netflix binge knows: buffering and dropped shows won’t cut it.
Movie Streaming Platform Triples Redundancy
Kanopy is a video streaming platform serving more than 4,000 libraries and 45 million patrons worldwide. In order for a film to be streamed without delays or buffering, it must first be transcoded, or broken up into smaller, compressed files known as “chunks.” A feature-length film may translate to thousands of five to 10-second chunks, and losing just one can cause playback issues that disrupt the customer viewing experience.
Kanopy used a provider that offered a CDN, origin storage, and transcoding all in one, but the provider lost chunks, disrupting the viewing experience. One thing their legacy CDN didn’t provide was backups. If the file couldn’t be located in their primary storage, it was gone.
They switched to a multi-cloud stack, engaging Cloudflare as a CDN and tripled their redundancy by using a cold archive, an origin store, and backup storage.
Gaming and CDN: Gaming platforms, too, have a heavy burden of graphics, images, and video to manage. They also need to deliver content fast and at speed or they risk games glitching up in the middle of a deciding moment.
Gaming Platform Wins When Games Go Viral
SIMMER.io is a community site that makes sharing Unity WebGL games easy for indie game developers. Whenever a game would go viral, their egress costs boiled over, hindering growth. SIMMER.io mirrored their data from Amazon S3 to Backblaze B2 and reduced egress to $0 as a result of the Bandwidth Alliance. They can now grow their site without having to worry about increasing egress costs over time or usage spikes when games go viral.
In addition to the types of companies listed above, financial institutions, media properties, mobile apps, and government entities can benefit from a CDN as well. However, a CDN is not going to be right for everyone. If your audience is hyper-targeted in a specific geographic location, you likely don’t need a CDN and can simply use a geolocated web host.
Pairing CDN With Cloud Storage
A CDN doesn’t cache every single piece of data一there will be times when a user’s request will be pulled directly from the origin store. Reliable, affordable, and performant origin storage becomes critical when the cache misses content. By pairing a CDN with origin storage in the cloud, companies can benefit from the elasticity and scalability of the cloud and the performance and speed of a CDN’s edge network.
Still wondering if a CDN is right for you? Let us know your questions in the comments.
A few weeks ago we published a post about why Backblaze chose not to farm Chia in our storage buffer. Our explanation was pretty simple: We agreed we weren’t in the game of currency speculation, so we just took the value and Netspace at the time and ran some math. In the end, it didn’t work for us, but our analysis isn’t the last word—we’re as curious as the next person as to what happens next with Chia.
The Chia Netspace slowed its exponential climb since we ran the post. At the time, it was increasing by about 33% each week. It’s now hovering between 31 and 33 exabytes, leaving us, and we presume a lot of other people, wondering what the future looks like for this cryptocurrency.
Jonmichael Hands, the VP of storage business development at Chia, reached out offering to discuss our post, and we figured he’d be a good guy to ask. So we gathered a few questions and sat down with him to learn more about what he sees on the horizon and what a wild ride it’s been so far.
Editor’s Note: This interview has been edited for length and clarity.
Q: What brought you to the Chia project?
I was involved in the beta about a year ago. It was right in the middle of COVID, so instead of traveling for work frequently, I built Chia farms in my garage and talked to a bunch of strangers on Keybase all night. At that time, the alpha version of the Chia plotter wrote six times more data than it writes today. I messaged the Chia president, saying, “You can’t release this software now. It’s going to obliterate consumer SSDs.” Prior to joining Chia, when I was at Intel, I did a lot of work on SSD endurance, so I helped Chia understand the software and how to optimize it for SSD endurance over the course of the year. Chia is an intersection of my primary expertise of storage, data centers, and cryptocurrencies—it was a natural fit, and I joined the team in May 2021.
Q: What was the outcome of that work to optimize the software?
Over the year, we got it down to about 1.3TB of writes, which is what it takes today. It’s still not a very friendly workload for consumer SSDs, and we definitely did not want people buying consumer SSDs and accidentally wearing them out for Chia. There has been a ton of community development in Chia plotters since the launch to further improve the performance and efficiency.
Q: That was a question we had, because Chia got a lot of backlash about people burning out consumer SSDs. What is your response to that criticism?
We did a lot of internal analysis to see if that was true, because we take it very seriously. So, how many SSDs are we burning out? I erred on the side of caution and assumed that 50% of the Netspace was farmed using consumer SSDs. I used the endurance calculator that I wrote for Chia on the wiki, which estimates how many plots you can write until the drive wears out. With 32 exabytes of Netspace, my math shows Chia wore out about 44,000 drives.
That seems high to me because I think consumers are smart. For the most part, I expect people have been doing their own research and buying the appropriate drives. We’ve also seen people plot on a consumer drive until it reaches a percentage of its useful life and then use it for something else. That’s a smart way to use new SSD drives—you get maximum use out of the hardware.
Companies are also offering plotting as a service. There are 50 or 60 providers who will just plot for you, likely using enterprise SSDs. So, I think 44,000 drives is a high estimate.
In 2021, there were 435 million SSD units shipped. With that many drives, how many SSD failures should we expect per year in total? We know the annualized failure rates, so it’s easy to figure out. Even in a best case scenario, I calculated there were probably 2.5 million SSD failures in 2021. If we created 44,000 extra failures, and that’s the high end, we’d only be contributing 1.5% of total failures.
Q: So, do you believe the e-waste argument is misplaced?
I’ve learned a lot about e-waste in the last few weeks. I talked to some e-waste facilities, and the amount of e-waste that SSDs create is small compared to other component parts, which is why SSD companies haven’t been attacked for e-waste before. They’re light and they don’t contain too many hazardous materials, comparatively. Most of them last five to 10 years as well. So we don’t believe there’s a large contribution from us in that area.
On the other hand, millions of hard drives get shredded each year, mostly by hyperscale data centers because end customers don’t want their data “getting out,” which is silly. I’ve talked to experts in the field, and I’ve done a lot of work myself on sanitization and secure erase and self-encrypting drives. With self-encrypting drives, you can basically instantly wipe the data and repurpose the drive for something else.
The data is erasure coded and encrypted before it hits the drive, then you can securely wipe the crypto key on the drive, making the data unreadable. Even then, tens of millions of drives are crushed every year, many of them for security reasons well before the end of their useful life. We think there’s an opportunity among those wasted drives.
Our team has a lot of ideas for how we could use Chia to accelerate markets for third-party recycled and renewed drives to get them back in the hands of Chia farmers and create a whole circular economy. If we’re successful in unlocking that storage, that will bring the cost of storage down. It will be a huge win for us and put us solidly on the right side of the e-waste issue.
Q: Did you expect the boom that happened earlier this summer and the spikes it created in the hard drive market?
Everybody at the company had their own Netspace model. My model was based off of the hard drive supply-demand sufficiency curve. If the market is undersupplied, prices go up. If the market’s vastly undersupplied, prices go up exponentially.
IDC says 1.2 zettabytes of hard drives are shipped every year, but the retail supply of HDDs is not very big. My model said when we hit 1% of the total hard drive supply for the year, prices are going to go up about 15%. If we hit 2% or 3%, prices will go up 30% to 40%. It turns out I was right that hard drive prices would go up, but I was wrong about the profitability.
It was the perfect black swan event. We launched the network on March 19 at 120 petabytes. Bitcoin was at an all-time high in April. We had this very low Netspace and this very high price. It created insane profitability for early farmers. Small farms were making $150,000 a day. People were treating it like the next Bitcoin, which we didn’t expect.
We went from 120 petabytes when we launched the network to 30 exabytes three months later. You can imagine I was a very popular guy in May. I was on the phone with analysts at Western Digital and Seagate almost every day talking about what was going to happen. When is it going to stop? Is it just going to keep growing forever?
It’s not shocking that it didn’t last long. At some point profitability gets impacted, and it starts slowing down.
Q: Where do you see hard drive demand going from here?
If the price doubles or triples in a very short amount of time, we might see a rush to go buy new hardware in the short term, but it will self-correct quickly. We’ll see Netspace acceleration in proportion. We predict the next wave of growth will come from smaller farmers and pools.
Bram [Cohen, the founder of Chia] hypothesized that underutilized storage space is ubiquitous. The majority of people aren’t using all of their hard drive space. IDC believes there’s about 500 exabytes of underutilized storage space sitting out in the world, so people have this equipment already. They don’t have to rush out and buy new hardware. That will largely be true for the next six months of growth. The first wave of growth was driven by new purchases. The next wave, and probably for the long term for Chia, will largely be driven by people who already have storage because the marginal cost is basically zero.
The demand for storage, overall, is increasing 20% to 30% every year, and hard drives are not getting 20% to 30% bigger every year. At some point, this inevitable squeeze was always going to happen where demand for storage exceeds supply. We want to figure out how we can grow sustainably and not impact that.
We have an interesting use case for old used drives, so we’re trying to figure out what the model is. There are certainly people who want to farm Chia on the enterprise scale, but it’s just not going to be cost-competitive to buy new drives long-term.
Q: Between the big enterprise farmers and the folks just happy to farm a few plots, do you have a preference?
Today, 37% of people are farming 10-50TB and 26% are farming 50-150TB. The remaining are big farmers. Technically, the smaller the farmer, the better. That means that we’re more decentralized. Our phase one was to build out the protocol and the framework for the most decentralized, secure blockchain in the world. In under three months, we’ve actually done that. One of the metrics of decentralization is how many full nodes you have. We’re approaching 350,000 full nodes. Just by pure metrics of decentralization we believe we are the most decentralized blockchain on the planet today.
Note: As of August 12, 2021, peak Bitcoin had 220K validators and now has about 65K. Chia’s peak was about 750K and it hovers around 450K.
In that respect, farming is actually one of the least interesting things we’re doing. It is a way to secure the network, and that’s been very novel. Today, if you want to launch a 51% attack, you have to buy 15 exabytes and get them up on the network. We think there’s definitely less than 100 data centers in the world that can host that many exabytes. Basically, the network has to be big enough where it can’t be attacked, and we think it’s there now. It’s very hard to attack a 30 exabyte network.
Q: We know you can’t speculate on future performance, but what does the future look like for Chia?
Our vision is to basically flip Ethereum within three years. Part of the business model will be having the support teams in place to help big financial institutions utilize Chia. We also think having a dedicated engineering team who are paid salaries is a good thing.
Our president thinks we’ll be known for Chialisp, which is the smart on-chain programming model. In the same way that everything’s a file in Linux, everything’s a coin in Chia. You can create what we call “Coloured Coins” or assets on the blockchain. So, you could tokenize a carbon credit. You could tokenize a Tesla stock. You can put those on the Chia blockchain and it just lives as a coin. Because it’s a coin, it natively swaps and is compatible with everything else on the blockchain. There’s no special software needed. Somebody could send it to another person with the standard Chia wallet because everything’s already integrated into the software. It’s very powerful for decentralized exchanges for some of this assetization and tokenization of different types of collateral on the blockchain.
Large financial institutions want to get involved with cryptocurrency, but there’s no play for them. All the financial institutions we’ve talked to have looked at Ethereum, but there are too many hacks. The code is too hard to audit. You need too much expertise to write it. And it consumes way too much energy. They’re not going to use a blockchain that’s not sustainable.
We are going to try to bridge that gap between traditional finance and the new world of cryptocurrency and decentralized finance. We think Chia can do that.
As big believers in open ecosystems, interoperability, and just making life easier for developers, Backblaze and Cloudflare share a lot—which means we’re always excited to dig into new functionality they’re providing for devs. When we heard about their new Logpush tool, I reached out to Tanushree Sharma, the product manager on this project, to learn more about why they built it, how it works with Backblaze B2 Cloud Storage, and what comes next.
Q: Tell us more about the origins of Logpush. How does it fit into the Cloudflare ecosystem and what problems is it solving for?
A: Cloudflare provides security, performance, and reliability services to customers behind our network. We analyze the traffic going through our network to perform actions such as routing traffic to the nearest data center, protecting against attacks, and blocking malicious bots. As part of providing these services for customers, we generate logs for every request in our network. Logpush makes these logs available for Enterprise customers to get visibility into their traffic, quickly and at scale.
Q: Cloudflare already offers Logpull, what’s the difference between that and Logpush?
A: Logpull requires customers to make calls to our Logpull API and then set up a storage platform and/or analytics tools to view the logs. Increasingly, we were hearing repeated use cases where customers would want to integrate with common log storage and analytics products. We also frequently heard that customers want their logs in real time or as near as possible. We decided to create Logpush to solve both these problems. Rather than the need for customers to configure and maintain a system that makes repeated API calls for the data, with Logpush, customers configure where they would like to send their logs and we push them there directly on their behalf.
Q: What makes it compelling to Cloudflare customers? Are there specific use cases you can touch on? Any light you can shed on how a beta tester used it when you first announced it?
A: Logpush makes it very easy for customers to export data. They simply set up a job using the Logpush API or with the click of a few buttons in the Cloudflare dashboard. From there, customers can combine Cloudflare logs with those of other tooling in their infrastructure, such as a SIEM or marketing tracking tools.
This combined data is very useful not only for day-to-day monitoring, but also when conducting network forensics after an attack. For example, a typical L7 DDoS attack originates from a handful of IP addresses. Customers can use platform-wide analytics to understand the activity of IP addresses from both within the Cloudflare network and other applications in their infrastructure. Platform-wide analytics are very powerful in giving customers a holistic view of their entire system.
Q: What sparked the push to support more S3-compatible storage destinations for Logpush data?
A: S3-compatible storage is becoming an industry standard for cloud storage. With the increased adoption of S3-compatible storage, we thought it would be a great spot for us to create our own endpoint to be able to serve more platforms.
Q: This isn’t the first time Backblaze and Cloudflare have worked together. In the spirit of building a better internet, we’ve helped a number of companies reduce data transfer fees via the Bandwidth Alliance. How did this affect your decision to include B2 Cloud Storage as one of these storage destinations and how is it serving Cloudflare and its customers’ needs?
A: Cloudflare values open ecosystems in technology—we believe that customers should not have to be locked in to any single provider. We started the Bandwidth Alliance to reduce or eliminate egress fees, which gives customers the ability to select a set of options that work best for them. With Backblaze as a long time Bandwidth Alliance member, including B2 Cloud Storage out of the gate was a no-brainer!
This case study on why Nodecraft made the switch from AWS S3 to Backblaze B2 Cloud Storage is a great illustration of how the Bandwidth Alliance can benefit customers.
Q: What was the process of integrating B2 Cloud Storage within the Logpush framework?
A: We worked with the great folks at Backblaze to integrate B2 Cloud Storage as a storage destination. This process began by modeling out costs, which were greatly reduced due to discounted egress costs as a result of the Bandwidth Alliance. For the S3-compatible integration, our team leveraged the AWS Go SDK to integrate with BackBlaze. Once we had verified that the integration was working, we created an intuitive UI-based workflow for our customers to make it easier for them to create and configure Logpush jobs.
Q: What can we look forward to as Logpush matures? Anything exciting on the horizon that you’d like to share?
A: One of the big areas that our team is focusing on is data sovereignty. We want customers to have control over where their data is stored and processed. We’re also working on building out Logpush by adding data sets and giving customers more customization with their logs.
Stay tuned to our Logs blog for upcoming releases!
Q: As a Cloudflare customer, where do I begin if I want to utilize Logpush? Walk us through the setup process of selecting B2 Cloud Storage as a destination for my logs.
In early startup stages, you’re developing the product, testing market fit, and refining your go-to-market strategy. Long-term infrastructure decisions may not even be on your radar, but if you want to scale beyond Series B, it pays to be planful before you’re locked in with a cloud services provider and storage costs are holding you back.
How will you manage your data? How much storage will you need to meet demand? Will your current provider continue to serve your use case? In this post, we’ll talk about how infrastructure decisions come into play in early startup development, the advantages of multi-cloud infrastructure, and best practices for implementing a multi-cloud system.
Infrastructure Planning: A Startup Timeline
Infrastructure planning becomes critical at three key points in early startup development:
In the pre-seed and seed stages.
When demand spikes.
When cloud credits run out.
Pre-seed and Seed Stages
Utilizing free cloud credits through a startup incubator like AWS Activate or the Google Cloud Startup Program at this stage of the game makes sense—you can build a minimum viable product without burning through outside investment. But you can’t rely on free credits forever. As you discover your market fit, you need to look for ways of sustaining growth and ensuring operating costs don’t get out of control later. You have three options:
Accept that you’ll stay with one provider, and manage the associated risks—including potentially high operating costs, lack of leverage, and high barriers to exit.
Plan for a migration when credits expire. This means setting up your systems with portability in mind.
Leverage free credits and use the savings to adopt a multi-cloud approach from the start with integrated providers.
Any of these options can work. What you choose is less important than the exercise of making a thoughtful choice and planning as though you’re going to be successful rather than relying on free credits and hoping for the best.
What Is Multi-cloud?
By the simplest definition, every company is probably a “multi-cloud” company. If you use Gmail for your business and literally any other service, you’re technically multi-cloud. But, for our purposes, we’re talking about the public cloud platforms you use to build your startup’s infrastructure—storage, compute, and networking. In this sense, multi-cloud means using two or more infrastructure as a service (IaaS) providers that complement each other rather than relying on AWS or Google to source all of the infrastructure and services you need in your tech stack.
Waiting Until Demand Spikes
Let’s say you decide to take full advantage of free credits, and the best possible outcome happens—your product takes off like wildfire. That’s great, right? Yes, until you realize you’re burning through your credits faster than expected and you have to scramble to figure out if your infrastructure can handle the demand while simultaneously optimizing spend. Especially for startups with a heavy data component like media, games, and analytics, increased traffic can be especially problematic—storage racks up, but more often, it’s egress fees that are the killer when data is being accessed frequently.
It’s not hard to find evidence of the damage that can occur when you don’t keep an eye on these costs:
The moment you’re successful can also be the moment you realize you’re stuck with an unexpected bill. Demand spikes, and cloud storage or egress overwhelms your budget. Consider the opposite scenario as well: What if your business experiences a downturn? Can you still afford to operate when cash flow takes a hit?
Waiting Until Cloud Credits Run Out
Sooner or later, free cloud credits run out. It’s extremely important to understand how the pricing model, pricing tiers, and egress costs will factor into your product offering when you get past “free.” For a lot of startups, these realities hit hard and fast—leaving developers seeking a quick exit.
Stay with your existing provider. This approach involves conducting a thorough audit of your cloud usage and potentially bringing in outside help to manage your spend.
Switch cloud providers completely. Weigh the cost of moving your data altogether versus the long-term costs of staying with your current provider. The barrier to exit may be high, but breakeven may be closer than you think.
Adopt an agnostic, multi-cloud approach. Determine the feasibility of moving parts of your infrastructure to different cloud providers to optimize your spend.
The Multi-cloud Guide for Startups
More companies have adopted a multi-cloud strategy in recent years. A 2020 survey by IDG found that 55% of organizations currently use multiple public clouds. The shift comes on the heels of two trends. First, AWS, Google, and Microsoft are no longer the only game in town. Innovative, specialized IaaS providers have emerged over the past decade and a half to challenge the incumbents. Second, after a period where many companies had to transition to the cloud, companies launching today are built to be cloud native. Without the burden of figuring out how to move to the cloud, they can focus on how best to structure their cloud-only environments to take advantage of the benefits multi-cloud infrastructure has to offer.
The Advantages of Multi-cloud
Improved Reliability: When your data is replicated in more than one cloud, you have the advantage of redundancy. If one cloud goes down, you can fall back to a second.
Disaster Recovery: With data in multiple, isolated clouds, you’re better protected from threats. If cybercriminals are able to access one set of your data, you’re more likely to recover if you can restore from a second cloud environment.
Greater Flexibility and Freedom: With a multi-cloud system, if something’s not working, you have more leverage to influence changes and the ability to leave if another vendor offers better features or more affordable pricing.
Affordability: It may seem counterintuitive that using more clouds would cost less, but it’s true. Vendors like AWS make their services hard to quit for a reason—when you can’t leave, they can charge you whatever they want. A multi-cloud system allows you to take advantage of industry partnerships and competitive pricing among vendors.
Best-of-breed Providers: Adopting a multi-cloud strategy means you can work with providers who specialize in doing one thing really well rather than doing all things just…kind of okay.
The advantages of a multi-cloud system have attracted an increasing number of companies and startups, but it’s not without challenges. Controlling costs, data security, and governance were named in the top five challenges in the IDG study. That’s why it’s all the more important to consider your cloud infrastructure early on, follow best practices, and plan ways to manage eventualities.
Multi-cloud Best Practices
As you plan your multi-cloud strategy, keep the following considerations in mind:
Cost Management: Cost management of cloud environments is a challenge every startup will face even if you choose to stay with one provider—so much so that companies make cloud optimization their whole business model. Set up a process to track your cloud utilization and spend early on, and seek out cloud providers that offer straightforward, transparent pricing to make budgeting simpler.
Data Security: Security risks increase as your cloud environment becomes more complex, and you’ll want to plan security measures accordingly. Ensure you have controls in place for access across platforms. Train your team appropriately. And utilize cloud functions like encryption and Object Lock to protect your data.
Governance: In an early stage startup, governance is going to be relatively simple. But as your team grows, you’ll need to have clear protocols for how your infrastructure is managed. Consider creating standard operating procedures for cloud platform management and provisioning now, when it’s still just one hat your CTO is wearing.
SIMMER.io: A Multi-cloud Use Case
SIMMER.io is a community site that makes sharing Unity WebGL games easy for indie game developers. Whenever games went viral, egress costs from Amazon S3 spiked—they couldn’t grow their platform without making a change. SIMMER.io mirrored their data to Backblaze B2 Cloud Storage and reduced egress to $0 as a result of the Bandwidth Alliance partnership between Backblaze and Cloudflare. They can grow their site without having to worry about increasing egress costs over time or usage spikes when games go viral, and they doubled redundancy in the process.
To learn more about how they configured their multi-cloud infrastructure to take advantage of $0 egress, download the SIMMER.io use case.
By making thoughtful choices about your cloud infrastructure and following some basic multi-cloud best practices, you plan as though you’re going to win from the start. That means deciding early on as to whether you’ll take cloud credits and stay with one provider, plan for multi-cloud, or some mix of the two along the way.
We recently spoke with Kristian Kielhofner, a developer and entrepreneur who’s on his third go-round as a startup founder and CEO after two very successful exits. He’s built a next-gen, crypto-centric media asset management platform, Tovera, which launched two days ago.
Developer customers are regularly choosing Backblaze B2 as the cloud storage platform that sits under their products and services. We feel lucky to learn about the innovations they are bringing to this world. Kristian found a clearer path to setting up CORS for B2 Cloud Storage and Cloudflare, so we asked him to share why he started Tovera, how he thought through his cloud storage options, and the exact steps he took to go live with his solution.
—Backblaze
The Tovera Backstory: Fighting Deepfakes
One morning, this story really caught my attention.
Like many technology enthusiasts, I’m familiar with deepfakes. That said, the “Pennsylvania Cheerleading Mom” story told me something: As we’ve seen time and time again, technology rapidly evolves beyond its original intended use. Sometimes for our benefit, and (unfortunately) sometimes not so much…
I realized it would only be a matter of time before this incredibly powerful technology would be in the hands of everyone—for uses good or evil. With more research, I found that (not surprisingly) the current approach to stopping misuse of the technology utilizes the same fundamental machine learning approaches powering the deepfakes themselves. It seems that what we now have is a machine learning arms race: a new model to generate deepfakes, a new model to detect them. Around and around we go.
I began thinking of approaching the deepfake problem from the other side of the coin. What if, instead of using machine learning to guess what is fake, we prove what is real? Deepfake detection models can’t provide 100% certainty today (or ever), but cryptographic authentication can. This simple idea was the genesis for Tovera.
What Does Tovera Do?
Tovera takes digital media you upload and uses existing cryptography and emerging blockchain technology to create a 100% secure validation record. When published on our platform, we can confirm (with 100% certainty) that your digital media assets are yours and haven’t been tampered with.
Tovera asset upload and management page.
After working through the initial proof of concept, I had another revelation: “Hey, while we’re hitting our API whenever and wherever digital media is viewed, why don’t we return some extra stuff?” Now, not only can our users validate that their content is really theirs and hasn’t been modified, they can use the features provided by Tovera Publish to dynamically update their released digital content from our dashboard. With Tovera, any changes you make to your digital media and online presence are updated across social media platforms, websites, and devices globally—instantly.
An image served via Tovera, with authentication dropdown.
In keeping with our mission of ensuring everyone can protect, validate, and control their online presence, we provide this technology for free with a simple sign up and onboarding process.
The Tovera Storage Journey
To provide this service, we needed to host the digital media files somewhere. Of course, you have your go-to juggernauts—Amazon, Google, and Microsoft. The problem is Tovera is a tiny startup. Having some prior startup experience, I know that spending your money and time wisely from the beginning is one of the most important things you can do.
I took one look at pricing from the “big three” cloud providers through the lens of someone who has experience buying bandwidth and storage (long story) and I thought, “Wow, this is a good business.” As has been covered on this blog and elsewhere, the storage and (especially) bandwidth markups from the big providers is, to put it mildly, significant.
Like some of you, I’ve also been a fan of Backblaze for a long time. Since it was announced, I’ve kept an eye on their B2 Cloud Storage product. So, one morning I took it upon myself to give Backblaze B2 a try.
Sign up and initial onboarding couldn’t have been easier. I found myself in the Backblaze B2 user dashboard up and running in no time. Creating application keys for my purposes was also extremely easy.
After deciding B2 Cloud Storage would work in theory, I decided to try it out in practice. As I integrated the service into Tovera, I ran into a few different vexing issues. I thought other devs might be able to benefit from my CORS troubleshooting, and so I’m outlining my experience here.
Checking the Backblaze S3 Compatible API
We make it simple for our users to upload their assets directly to our cloud storage provider. Because B2 Cloud Storage has the Backblaze S3 Compatible API, the use of presigned URLs fits the bill. This way, Tovera users can upload their digital media assets directly to Backblaze, securely, and make them available to the world via our platform.
In case you’re not familiar with the presigned URL process, the overall flow looks something like the structure laid out in this blog post.
After perusing the available documentation, I started off with the following Node.js Javascript code:
With this Javascript function, Tovera API services provide a URL for our user dashboard to instantly (and securely) upload their assets to our Backblaze account. I had read Backblaze B2 has a 100% Amazon S3 Compatible API but I was a little skeptical. Is this really going to work? Sure enough, it worked on the first attempt!
Integrating Cloudflare and Setting Up CORS
Between the Bandwidth Alliance and having dealt with DDoS attacks and shady internet stuff in general before, I’m also a big fan of Cloudflare. Fortunately, Backblaze provides guidance on how to best use B2 Cloud Storage with Cloudflare to make use of their combined power.
Once I set up Cloudflare to work with B2 Cloud Storage and the Tovera API services were returning valid, presigned URLs for clients to do a direct HTTP PUT, I tried it out in our Next.js-powered user dashboard.
Uh-oh. Dreaded CORS errors. I’ll spare you the details, but here’s where things get interesting… I don’t know about you, but CORS can be a little frustrating. LONG story short, I dug in deep, feeling a little like I was wandering around a dark room looking for the light switch.
With this usage of the Backblaze B2 command line utility, we’re setting the following CORS rules on our bucket:
Allow users to download Backblaze B2 files from anywhere using the native B2 Cloud Storage interfaces.
Allow users to use the Backblaze S3 Compatible API to download and upload their files from anywhere with the authenticated presigned URL provided by the server side Javascript function above.
With these rules, Tovera users can use our embeddable verification links across any site they provide them to—existing websites, social media networks, and more. In other applications you may want to limit these CORS rules to what makes sense for your use case.
Focusing on What’s Important
With Backblaze B2, we at Tovera can focus on our mission of putting our digital media security, validation, and publishing functionality in the hands of as many people as possible. Tovera users can take back control of their online presence and address the many threats posed by deepfake technologies that threaten their likeness, reputation, and brand.
Kristian Kielhofner works on overall technical architecture, vision, and strategy for Tovera when he’s not out buying yet another whiteboard to scribble on. Kristian previously built, grew, and exited Star2Star Communications—a leading provider of business productivity solutions.
As of June 30, 2021, Backblaze had 181,464 drives spread across four data centers on two continents. Of that number, there were 3,298 boot drives and 178,166 data drives. The boot drives consisted of 1,607 hard drives and 1,691 SSDs. This report will review the quarterly and lifetime failure rates for our data drives, and we’ll compare the failure rates of our HDD and SSD boot drives. Along the way, we’ll share our observations of and insights into the data presented and, as always, we look forward to your comments below.
Q2 2021 Hard Drive Failure Rates
At the end of June 2021, Backblaze was monitoring 178,166 hard drives used to store data. For our evaluation, we removed from consideration 231 drives which were used for either testing purposes or as drive models for which we did not have at least 60 drives. This leaves us with 177,935 hard drives for the Q2 2021 quarterly report, as shown below.
Notes and Observations on the Q2 2021 Stats
The data for all of the drives in our data centers, including the 231 drives not included in the list above, is available for download on the Hard Drive Test Data webpage.
Zero Failures
Three drive models recorded zero failures during Q2, let’s take a look at each.
6TB Seagate (ST6000DX000): The average age of these drives is over six years (74 months) and with one failure over the last year, this drive is aging quite well. The low number of drives (886) and drive days (80,626) means there is some variability in the failure rate, but the lifetime failure rate of 0.92% is solid.
12TB HGST (HUH721212ALE600): These drives reside in our Dell storage servers in our Amsterdam data center. After recording a quarterly high of five failures last quarter, they are back on track with zero failures this quarter and a lifetime failure rate of 0.41%.
16TB Western Digital (WUH721816ALE6L0): These drives have only been installed for three months, but no failures in 624 drives is a great start.
Honorable Mention
Three drive models recorded one drive failure during the quarter. They vary widely in age.
On the young side, with an average age of five months, the 16TB Toshiba (MG08ACA16TEY) had its first drive failure out of 1,430 drives installed.
At the other end of the age spectrum, one of our 4TB Toshiba (MD04ABA400V) drives finally failed, the first failure since Q4 of 2018.
In the middle of the age spectrum with an average of 40.7 months, the 8TB HGST drives (HUH728080ALE600) also had just one failure this past quarter.
Outliers
Two drive models had an annualized failure rate (AFR) above 4%, let’s take a closer look.
The 4TB Toshiba (MD04ABA400V) had an AFR of 4.07% for Q2 2021, but as noted above, that was with one drive failure. Drive models with low drive days in a given period are subject to wide swings in the AFR. In this case, one less failure during the quarter would result in an AFR of 0% and one more failure would result in an AFR of over 8.1%.
The 14TB Seagate (ST14000NM0138) drives have an AFR of 5.55% for Q2 2021. These Seagate drives along with 14TB Toshiba drives (MG07ACA14TEY) were installed in Dell storage servers deployed in our U.S. West region about six months ago. We are actively working with Dell to determine the root cause of this elevated failure rate and expect to follow up on this topic in the next quarterly drive stats report.
Overall AFR
The quarterly AFR for all the drives jumped up to 1.01% from 0.85% in Q1 2021 and 0.81% one year ago in Q2 2020. This jump ended a downward trend over the past year. The increase is within our confidence interval, but bears watching going forward.
HDDs vs. SSDs, a Follow-up
In our Q1 2021 report, we took an initial look at comparing our HDD and SSD boot drives, both for Q1 and lifetime timeframes. As we stated at the time, a numbers-to-numbers comparison was suspect as each type of drive was at a different point in its life cycle. The average age of the HDD drives was 49.63 months while the SSDs average age was 12.66 months. As a reminder, the HDD and SSD boot drives perform the same functions which include booting the storage servers and performing reads, writes, and deletes of daily log files and other temporary files.
To create a more accurate comparison, we took the HDD boot drives that were in use at the end of Q4 2020 and went back in time to see where their average age and cumulative drive days would be similar to those same attributes for the SDDs at the end of Q4 2020. We found that at the end of Q4 2015 the attributes were the closest.
Let’s start with the HDD boot drives that were active at the end of Q4 2020.
Next, we’ll look at the SSD boot drives that were active at the end of Q4 2020.
Finally, let’s look at the lifetime attributes of the HDD drives active in Q4 2020 as they were back in Q4 2015.
To summarize, when we control using the same drive models, the same average drive age, and a similar number of drive days, HDD and SSD drives failure rates compare as follows:
While the failure rate for our HDD boot drives is nearly two times higher than the SSD boot drives, it is not the nearly 10 times failure rate we saw in the Q1 2021 report when we compared the two types of drives at different points in their lifecycle.
Predicting the Future?
What happened to the HDD boot drives from 2016 to 2020 as their lifetime AFR rose from 1.54% in Q4 2015 to 6.26% in Q4 2020? The chart below shows the lifetime AFR for the HDD boot drives from 2014 through 2020.
As the graph shows, beginning in 2018 the HDD boot drive failures accelerated. This continued in 2019 and 2020 even as the number of HDD boot drives started to decrease when failed HDD boot drives were replaced with SSD boot drives. As the average age of the HDD boot drive fleet increased, so did the failure rate. This makes sense and is borne out by the data. This raises a couple of questions:
Will the SSD drives begin failing at higher rates as they get older?
How will the SSD failure rates going forward compare to what we have observed with the HDD boot drives?
We’ll continue to track and report on SSDs versus HDDs based on our data.
Lifetime Hard Drive Stats
The chart below shows the lifetime AFR of all the hard drive models in production as of June 30, 2021.
Notes and Observations on the Lifetime Stats
The lifetime AFR for all of the drives in our farm continues to decrease. The 1.45% AFR is the lowest recorded value since we started back in 2013. The drive population spans drive models from 4TB to 16TB and varies in average age from three months (WDC 16TB) to over six years (Seagate 6TB).
Our best performing drive models in our environment by drive size are listed in the table below.
Notes:
The WDC 16TB drive, model: WUH721816ALE6L0, does not appear to be available in the U.S. through retail channels at this time.
Status is based on what is stated on the website. Further investigation may be required to ensure you are purchasing a new drive versus a refurbished drive marked as new.
The source and price were as of 7/30/2021.
In searching for the Toshiba 16TB drive, model: MG08ACA16TEY, you may find model: MG08ACA16TE for much less ($399.00 or less). These are not the same drive and we have no information on the latter model. The MG08ACA16TEY includes the Sanitize Instant Erase feature.
The Drive Stats Data
The complete data set used to create the information used in this review is available on our Hard Drive Test Data page. You can download and use this data for free for your own purpose. All we ask are three things: 1) you cite Backblaze as the source if you use the data, 2) you accept that you are solely responsible for how you use the data, and 3) you do not sell this data to anyone; it is free.
In an era when ransomware and cybersecurity attacks on K-12 schools have nearly quadrupled, backups are critical. Today, advances in cloud backup technology like immutability and Object Lock allow school districts to take advantage of the benefits of cloud infrastructure while easing security concerns about sensitive data.
School districts have increasingly adopted cloud-based software as a service applications like video conferencing, collaboration, and learning management solutions, but many continue to operate with legacy on-premises solutions for backup and disaster recovery. If your district is ready to move your backup and recovery infrastructure to the cloud, how do you choose the right cloud partners and protect your school district’s data?
This post explains the benefits school districts can realize from moving infrastructure to the cloud, considerations to evaluate when choosing a cloud provider, and steps for preparing for a cloud migration at your district.
The Benefits of Moving to the Cloud for School Districts
Replacing legacy on-premises tape backup systems or expensive infrastructure results in a number of benefits for school districts, including:
Reduced Capital Expenditure (CapEx): Avoid major investments in new infrastructure.
Budget Predictability: Easily plan for predictable, recurring monthly expenses.
Cost Savings: Pay as you go rather than paying for unused infrastructure.
Elasticity: Scale up or down as seasonal demand fluctuates.
Workload Efficiencies: Refocus IT staff on other priorities rather than managing hardware.
Centralized Backup Management: Manage your backups in a one-stop shop.
Ransomware Protection: Stay one step ahead of hackers with data immutability.
Reduced CapEx. On-premises infrastructure can cost hundreds of thousands of dollars or more, and that infrastructure will need to be replaced or upgraded at some point. Rather than recurring CapEx, the cloud shifts IT budgets to a predictable, monthly operating expenses (OpEx) model. You no longer have to compete with other departments for a share of the capital projects budget to upgrade or replace expensive equipment.
Cloud Migration 101: Kings County
John Devlin, CIO of Kings County, was facing an $80,000 bill to replace all of the physical tapes they used for backups as well as an out-of-warranty tape drive all at once. He was able to avoid the bill by moving backup infrastructure to the cloud.
Costs are down, budgets are predictable, and the move freed up his staff to focus on bigger priorities. He noted, “Now the staff is helping customers instead of playing with tapes.”
Budget Predictability. With cloud storage, if you can accurately anticipate data usage, you can easily forecast your cloud storage budget. Since equipment is managed by the cloud provider, you won’t face a surprise bill when something breaks.
Cost Savings. Even when on-premises infrastructure sits idle, you still pay for its maintenance, upkeep, and power usage. With pay-as-you-go pricing, you only pay for the cloud storage you use rather than paying up front for infrastructure and equipment you may or may not end up needing.
Elasticity. Avoid potentially over-buying on-premises equipment since the cloud provides the ability to scale up or down on demand. If you create less data when school is out of session, you’re not paying for empty storage servers to sit there and draw down power.
Workload Efficiencies. Rather than provisioning and maintaining on-premises hardware or managing a legacy tape backup system, moving infrastructure to the cloud frees up IT staff to focus on bigger priorities. All of the equipment is managed by the cloud provider.
Centralized Backup Management. Managing backups in-house across multiple campuses and systems for staff, faculty, and students can quickly become a huge burden, so many school districts opt for a backup software solution that’s integrated with cloud storage. The integration allows them to easily tier backups to object storage in the cloud. Veeam is one of the most common providers of backup and replication solutions. They provide a one-stop shop for managing backups—including reporting, monitoring, and capacity planning—freeing up district IT staff from hours of manual intervention.
Ransomware Protection.With schools being targeted more than ever, the ransomware protection provided by some public clouds couldn’t be more important. Tools like Object Lock allow you to recreate the “air gap” protection that tape provides, but it’s all in the cloud. With Object Lock enabled, no one can modify, delete, encrypt, or tamper with data for a specific amount of time. Any attempts by a hacker to compromise backups will fail in that time. Object Lock works with offerings like immutability from Veeam so schools can better protect backups from ransomware.
An Important Distinction: Sync vs. Backup
Keep in mind, solutions like Microsoft OneDrive, DropBox, and Google Drive, while enabling collaboration for remote learning, are not the same as a true backup. Sync services allow multiple users across multiple devices to access the same file—which is great for remote learning, but if someone accidentally deletes a file from a sync service, it’s gone. Backup stores a copy of those files somewhere remote from your work environment, oftentimes in an off-site server—like cloud storage. It’s important to know that a “sync” is not a backup, but they can work well together when properly coordinated. You can read more about the differences here.
Considerations for Choosing a Cloud Provider for Your District
Moving to the cloud to manage backups or replace on-premises infrastructure can provide significant benefits for K-12 school districts, but administrators should carefully consider different providers before selecting one to trust with their data. Consider the following factors in an evaluation of any cloud provider:
Security: What are the provider’s ransomware protection capabilities? Does the provider include features like Object Lock to make data immutable? Only a few providers offer Object Lock, but it should be a requirement on any school district’s cloud checklist considering the rising threat of ransomware attacks on school districts. During 2020, the K-12 Cybersecurity Resource Center cataloged 408 publicly-disclosed school incidents versus 122 in 2018.
Compliance: Districts are subject to local, state, and federal laws including HIPAA, so it’s important to ensure a cloud storage provider will be able to comply with all pertinent rules and regulations. Can you easily set lifecycle rules to retain data for specific retention periods to comply with regulatory requirements? How does the provider handle encryption keys, and will that method meet regulations?
Ease of Use: Moving to the cloud means many staff who once kept all of your on-premises infrastructure up and running will instead be managing and provisioning infrastructure in the cloud. Will your IT team face a steep learning curve in implementing a new storage cloud? Test out the system to evaluate ease of use.
Pricing Transparency: With varying data retention requirements, transparent pricing tiers will help you budget more easily. Understand how the provider prices their service including fees for things like egress, required minimums, and other fine print. And seek backup providers that offer pricing sensitive to educational institutions’ needs. Veeam, for example, offers discounted public sector pricing allowing districts to achieve enterprise-level backup that fits within their budgets.
Integrations/Partner Network: One of the risks of moving to the cloud is vendor lock-in. Avoid getting stuck in one cloud ecosystem by researching the providers’ partner network and integrations. Does the provider already work with software you have in place? Will it be easy to change vendors should you need to?
Support: Does your team need access to support services? Understand if your provider offers support and if that support structure will fit your team’s needs.
As you research and evaluate potential cloud providers, create a checklist of the considerations that apply to you and make sure to clearly understand how the provider meets each requirement.
Preparing for a Cloud Migration at Your School District
Even when you know a cloud migration will benefit your district, moving your precious data from one place to another can be daunting at the least. Even figuring out how much data you have can be a challenge, let alone trying to shift a culture that’s accustomed to having hardware on-premises. Having a solid migration plan helps to ensure a successful transition. Before you move your infrastructure to the cloud, take the time to consider the following:
Conduct a thorough data inventory: Make a list of all applications with metadata including the size of the data sets, where they’re located, and any existing security protocols. Are there any data sets that can’t be moved? Will the data need to be moved in phases to avoid disruption? Understanding what and how much data you have to move will help you determine the best approach.
Consider a hybrid approach: Many school districts have already invested in on-premises systems, but still want to modernize their infrastructure. Implementing a hybrid model with some data on-premises and some in the cloud allows districts to take advantage of modern cloud infrastructure without totally abandoning systems they’ve customized and integrated.
Test a proof of concept with your new provider: Migrate a portion of your data while continuing to run legacy systems and test to compare latency, interoperability, and performance.
Plan for the transfer: Armed with your data inventory, work with your new provider to plan the transfer and determine how you’ll move the data. Does the provider have data transfer partners or offer a data migration service above a certain threshold? Make sure you take advantage of any offers to manage data transfer costs.
Execute the migration and verify results: Schedule the migration, configure your transfer solution appropriately, and run checks to ensure the data migration was successful.
An Education in Safe, Reliable Cloud Backups
Like a K-12 school district, Coast Community College District (CCCD) manages data for multiple schools and 60,000+ students. With a legacy on-premises tape backup system, data recovery often took days and all too often failed at that. Meanwhile, staff had to chauffeur tapes from campus to campus for off-site backup data protection. They needed a safer, more reliable solution and wanted to replace tapes with cloud storage.
CCCD implemented Cohesity backup solutions to serve as a NAS device, which will eventually replace 30+ Windows file servers, and eliminated tapes with Backblaze B2 Cloud Storage, safeguarding off-site backups by moving the data farther away. Now, restoring data takes seconds instead of days, and staff no longer physically transfer tapes—it all happens in the cloud.
How Cloud Storage Can Protect School District Data
Cloud-based solutions are integral to successful remote or hybrid learning environments. School districts have already made huge progress in moving to the cloud to enable remote learning. Now, they have the opportunity to capitalize on the benefits of cloud storage to modernize infrastructure as ransomware attacks become all the more prevalent. To summarize, here are a few things to remember when considering a cloud storage solution:
Using cloud storage with Object Lock to store an off-site backup of your data means hackers can’t encrypt, modify, or delete backups within a set timeframe, and schools can more easily restore backups in the event of a disaster or ransomware attack.
Increased ransomware protections allow districts to access the benefits of moving to the cloud like reduced CapEx, workflow efficiencies, and cost savings without sacrificing the security of air gapped backups.
Evaluate a provider’s security offerings, compliance capability, ease of use, pricing tiers, partner network, and support structure before committing to a cloud migration.
Take the time to plan your migration to ensure a successful transition.
Have more questions about cloud storage or how to implement cloud backups in your environment? Let us know in the comments. Ready to get started?
I am a sucker for a factory tour. I marvel with wide-eyed wonder as I watch how pieces and parts get created, assembled, and tested into something you can recognize and use. Whether it’s making beer or cars—sign me up. So, when Seagate Technology offered me a chance to tour their hard drive prototyping facility in Longmont, Colorado, I was powerless to resist. After all, I’d get to see how they prototype the process for building hard drives before they scale to full production. As a bonus, I also got to see their reliability lab and to talk with them about how they perform fault analysis on failed drives, but I’ll save those topics for a future post. For now, put on your lab coat and follow me to Longmont, the tour is starting.
Welcome to Longmont
Over the past 40 years, Longmont, Colorado has been home to multiple hard drive manufacturers. This accounts for the hard drive-related talent that lives in this pastoral community where such skills might otherwise be hard to find. Longmont has also come a long way from the brick shipping days of MiniScribe in the 80s to today’s ultra-sophisticated factories like the Seagate facility I have been invited to tour.
I arrive at the front desk with appointment confirmation in hand—you can’t just show up. I present appropriate credentials, electronically sign a non-disclosure agreement, get my picture taken, receive my badge—escort only—and wait for the host to arrive. I’m joined by my Backblaze colleague, Ariel, our senior director of supply chain, and a few minutes later our host arrives. Before we start, we get the rules: No pictures, in fact devices such as cell phones and tablets have to be put away. I’ll take notes, which I’ll do on my 3×5 Backblaze notepad.
My notes (as such) from the tour. Yes, there are two page three’s…
The Prototyping Line
The primary functions of the prototyping line are to define, optimize, and standardize the build processes, tooling, and bill of materials needed for the mass production of hard drives by various Seagate manufacturing facilities around the globe. In addition, the prototyping line is sometimes used to test the design and assembly of new hard drive components.
The components of a typical hard drive are:
The casing.
The platter (for storing data).
The spindle (for spinning the platters).
The head stack assembly comprised of:
The read/write arm and heads (to read and write data).
The actuator (for controlling the actions of the read/write arm).
Circuit board(s) and related electronics.
The prototyping line is a single assembly line comprised of stations that perform the various functions needed to build a hard drive—actually, many different models of 3.5in hard drives. Individual stations decide whether or not to operate on the drive based on the routing assigned to the drive. A given station can be used all of the time to do the same thing, used all the time to do a variation of the task, or used some of the time. For example, installing a serial number is done for every drive; installing drive platters is done for every drive, but can vary by the number of platters to be installed; and installing a second actuator is only required for those drives with dual actuators.
A Seagate employee likened the process to a one-way salad bar: All salads being made pass through the same sequence of steps, but not every salad gets every ingredient. As you travel down the salad bar line, you will always get several common ingredients such as a tray, a plate, a fork, lettuce, and so on. And while you always get salad dressing, you may get a different one each time. Finally, there are some ingredients like garbanzo beans or broccoli that you will never get, but the person behind you making their own salad will.
Just like a salad bar line, the prototyping line is designed to be configured to handle a large number of permutations when building a hard drive. This flexibility is important as Seagate introduces new technologies which may require changes to stations or even new stations to be created and integrated into the line.
At first blush, assembling a hard drive is nothing more than a series of incremental steps accomplished in a precise order. But there are multiple layers at work here. At the first station, we can see the simple task of picking up a motor base assembly (aka a baseplate) from a storage bin and placing it correctly on the conveyor belt to the next station. We can see the station perform perhaps 20 visibly discrete operations to accomplish this task: Move the pickup arm to the left, open the pickup mechanism, lower the arm, close the pickup mechanism around the baseplate, and so on. Beyond what we can see, for each movement of the station, there are electro-mechanical components driving those observable operations, and many operations we don’t readily see. And beyond that, controlling the components, are layers of firmware, software, and machine code orchestrating the 20 or so simple movements we do see. As we slowly shuffle from window to window gawking at each station performing its specific task, a hard drive of amazing complexity emerges in front of our eyes.
Finally, the prototyping line is used from time-to-time to assist in and validate design and build decisions. For example, the assembly line could be used to inform on the specific torque used on a fastener to determine torque retention over thermal/altitude cycles. In another example, the prototyping line could be used to assess cleanliness and manufacturability as a function of the material selected for a particular component.
Facts About the Longmont Line
The Longmont prototyping line is the longest Seagate assembly line. This is because the line needs to be able to assemble a variety of different drive models whereas a factory-based assembly line only needs to assemble one or two models at a time.
The Longmont prototyping line assembles 3.5in hard drives. The prototyping line for their 2.5in drives is in their Minnesota facility.
All of the stations on the line are designed by Seagate.
All of the software used to control the stations is designed and built by Seagate.
All of the stations in the cleanroom are modular and can be pulled from the line or moved to a different position in the assembly sequence if needed.
On average, it takes about five minutes for a drive to make its way through the entire line.
The floor is built upon a unique pier design to help minimize the transfer of vibrations from machine to machine and from people to machines.
Beyond the Line
As we reach the end of windows and the cleanroom, you might assume our tour is done. Au contraire, there’s another door. A badge swipe and we enter into a large room located just after the cleanroom. We are in the testing room. To understand what happens here, let’s take a step back in the process.
One of the primary functions of the prototyping line is to define the build process for use by factories around the world. Let’s say the line is prototyping the build of 500 drives of model XYZ. One of the last steps in the assembly process is to attach the process drive cover to enclose the drive components, and in our example, our model XYZ drives are filled with helium and sealed. Once the assembly process is complete, the drives are moved from the cleanroom to the testing room.
The most striking feature of the testing room is that it contains row after row of what appear to be little black boxes, stacked 40 to 50 high. Visually, each row looks like a giant wall of post office boxes.
Each post office box is a testing unit and holds one 3.5in hard drive. Inside each box are connections for a given drive model which, once connected, can run predefined test scenarios to exercise the drive inside. Load the firmware, write some data, read some data, delete some data, repeat, all while the drives are monitored to see if they are performing as expected. Easy enough, but there’s more. Each testing box can also control the temperature inside. Based on the testing plan, the temperature and test duration are dialed-in by the testing operator and testing begins. Testing in this manner typically runs for a couple of weeks and thousands of drives can be tested during this time with different tests being done on different groups of drives.
Once this first round of testing is complete on our model XYZ drives, a review is done to determine if they qualify to move on—too many failures during testing and it’s back to the proverbial drawing board, or at least the prototyping stage. Assuming our model XYZ drives pass the muster, they move on. At that point, the final cover is installed over the top of the process cover and the drives which contain helium are leak tested. All drives are then returned to the post office boxes for a quick round of testing. If everything goes according to plan, then model XYZ is ready for production—well, maybe not. The entire process, from assembly to testing, is repeated multiple times with each round being compared to the previous rounds to ensure consistency.
What happens to all the drives that Longmont produces? Good question. If they fail during the assembly process, the process engineer in charge of the product, who is usually on the cleanroom floor during the assembly process, steps in. Many issues can be fixed on the spot and the assembly process continues, but for some failures a design issue is the culprit. In that case the assembly process is stopped, and the feedback is passed back to the designers so they can correct the flaw. The same is basically true for drives which fail the testing process, the design engineers are informed of the results and can review the analytics compiled from the testing boxes.
If a given cohort of drives is successfully assembled and passes their testing plan, they could be sent to specific customers as testing units, or used for firmware testing, or be sent to the reliability lab, or they could just be recycled. The hard drives produced on the Longmont prototyping line are not production units, that’s where the factories come in.
Mass Quantities
Once Seagate is satisfied that the prototyping line can consistently produce hard drives which meet their qualifications, it is time to roll out the line to its factories. More accurately, a given factory will convert one or more of its lines to build the new product (model). To do this, they incorporate the processes developed and tested on the Longmont prototyping line, including any physical, firmware, and software changes to the various stations in the factory which will assemble the new product. On rare occasions, new stations are introduced and others are removed, but a majority of the time the factory is updating existing equipment as noted. Depending on the amount of change to the factory line, it can take anywhere from a couple of days to a couple of weeks to get the line up and running to produce drives which meet the standards defined by the prototyping line we just toured in Longmont. To make sure those standards are met, each factory has thousands upon thousands of testing boxes to test each drive coming off the factory assembly line. Only after they pass the predefined testing protocol are they shipped to distribution centers and, eventually, customers.
Next Up: The Reliability Lab
That’s the end of the tour today, next time we’ll wander through the Seagate reliability lab also at Longmont to see what happens when you heat, drop, fling, vibrate, and otherwise torture a hard drive. Good times.
Author’s Note: I wish to thank Robert who made this tour happen in the first place, Kent, Gregory, Jason, and Jen who were instrumental in reviewing this material to make sure I had it right, and the other unnamed Seagate folks who helped along the way. Thank you all.
The arrival of Chia on the mainstream media radar brought with it some challenging and interesting questions here at Backblaze. As close followers of the hard drive market, we were at times intrigued, optimistic, cautious, concerned, and skeptical—often all at once. But, our curiosity won out. Chia is storage-heavy. We are a storage company. What does this mean for us? It was something we couldn’t ignore.
Backblaze has over an exabyte of data under management, and we typically maintain around three to four months worth of buffer space. We wondered—with this storage capacity and our expertise, should Backblaze farm Chia?
For customers who are ready to farm, we recently open-sourced software to store Chia plots using our cloud storage service, Backblaze B2. But deciding whether we should hop on a tractor and start plotting ourselves required a bunch of analysis, experimentation, and data crunching—in short, we went down the rabbit hole.
After proving out if this could work for our business, we wanted to share what we learned along the way in case it was useful to other teams pondering data-heavy cloud workloads like Chia.
Grab your gardening gloves, and we’ll get into the weeds.
Here’s a table of contents for those who want to go straight to the analysis:
If you’re new to the conversation, here’s a description of what Chia is and how it works. Feel free to skip if you’re already in the know.
Chia is a cryptocurrency that employs a proof of space and time algorithm that is billed as a greener alternative to coins like Bitcoin or Ethereum—it’s storage-intensive rather than energy-intensive. There are two ways to play the Chia market: speculating on the coin or farming plots (the equivalent of “mining” other cryptocurrencies). Plots can be thought of as big bingo cards with a bunch of numbers. The Chia Network issues match challenges, and if your plot has the right numbers, you win a block reward worth two Chia coins.
Folks interested in participating need to be able to generate plots (plotting) and store them somewhere so that the Chia blockchain software can issue match challenges (farming). The requirements are pretty simple:
A computer running Windows, MacOS, or Linux with an SSD to generate plots.
HDD storage to store the plots.
Chia blockchain software.
But, as we’ll get into, things can get complicated, fast.
Should Backblaze Support and Farm Chia?
The way we saw it, we had two options for the role we wanted to play in the Chia market, if at all. We could:
Enable customers to farm Chia.
Farm it ourselves using our B2 Native API or by writing directly to our hard drives.
Helping Backblaze Customers Farm
We didn’t see it as an either/or, and so, early on we decided to find a way to enable customers to farm Chia on Backblaze B2. There were a few reasons for this choice:
We’re always looking for ways to make it easy for customers to use our storage platform.
With Chia’s rapid rise in popularity causing a worldwide shortage of hard drives, we figured people would be anxious for ways to farm plots without forking out for hard drives that had jumped up $300 or more in price.
Once you create a plot, you want to hang onto it, so customer retention looked promising.
The Backblaze Storage Cloud provides the keys for successful Chia farming: There is no provisioning necessary, so Chia farmers can upload new plots at speed and scale.
However, Chia software was not designed to allow farming with public cloud object storage. On a local storage solution, Chia’s quality check reads, which must be completed in under 28 seconds, can be cached by the kernel. Without caching optimizations and a way to read plots concurrently, cloud storage doesn’t serve the Chia use case. Our early tests confirmed this, taking longer than the required 28 seconds.
So our team built an experimental workaround to parallelize operations and speed up the process, which you can read more about here. Short story: The experiment has worked, so far, but we’re still in a learning mode about this use case.
Should Backblaze Farm?
Enabling customers to farm Chia was a fun experiment for our Engineering team, but deciding whether we could or should farm Chia ourselves took some more thinking. First, the pros:
We maintain a certain amount of buffer space. It’s an important asset to ensure we can scale with our customer’s needs. Rather than farming in a speculative fashion and hoping to recoup an investment in farming infrastructure, we could utilize the infrastructure we already have, which we could reclaim at any point. Doing so would allow us to farm Chia in a non-speculative fashion more efficiently than most Chia farmers.
Farming Chia could make our buffer space profitable when it would otherwise be sitting on the shelves or drawing down power in the live buffer.
When we started investigating Chia, the Chia Calculator said we could potentially make $250,000 per week before expenses.
These were enticing enough prospects to generate significant debate on our leadership team. But, we might be putting the cart before the horse here… While we have loads of HDDs sitting around where we could farm Chia plots, we first needed a way to create Chia plots (plotting).
The Challenges of Plotting
Generating plots at speed and scale introduces a number of issues:
It requires a lot of system resources: You need a multi-core processor with fast cores so you can make multiple plots at once (parallel plotting) and a high amount of RAM.
It quickly wears out expensive SSDs: Plotting requires at least 256.6GB of temporary storage, and that temporary storage does a lot of work—about 1.8TB of reading and writing. An HDD can only read/write at 120 MB/s. So, people typically use SSDs to plot, and particularly NVMe drives which are much faster than HDD, often over 3000 MB/s. While SSD drives are fast, they wear out like tires. They’re not defective, reading and writing at the pace it takes to plot Chia just burns them out. Some reports estimate four weeks of useful farming life, and it’s not advisable to use consumer SSDs for that reason.
At Backblaze, we have plenty of HDDs, but not many free SSDs. Thus, we’d need to either buy (and wear out) a bunch of SSDs, or use a cloud compute provider to generate the plots for us.
The first option would take time and resources to build enough plotters in each of our data centers across the country and in Europe, and we could potentially be left with excess SSDs at the end. The second would still render a bunch of SSDs useless, albeit not ours, and it would be costly.
Still, we wondered if it would be worth it given the Chia Calculator’s forecasts.
The Challenges of Farming
Once we figured out a way to plot Chia, we then had a few options to consider for farming Chia: Should we farm by writing directly to the extra hard drives we had on the shelves, or by using our B2 Native API to fill the live storage buffer?
Writing directly to our hard drives posed some challenges. The buffer drives on the shelf eventually do need to go into production. If we chose this path, we would need a plan to continually migrate the data off of drives destined for production to new drives as they come in. And we’d need to dedicate staff resources to manage the process of farming on the drives without affecting core operations. Reallocating staff resources to a farming venture could be seen as a distraction, but a worthy one if it panned out. We once thought of developing B2 Cloud Storage as a distraction when it was first suggested, and today, it’s integral to our business. That’s why it’s always worth considering these sorts of questions.
Farming Chia using the B2 Native API to write to the live storage buffer would pull fewer staff resources away from other projects, at least once we figured out our plotting infrastructure. But we would need a way to overwrite the plots with customer data if demand suddenly spiked.
And the Final Question: Can We Make Money?
Even with the operational challenges above and the time it would take to work through solutions, we still wondered if it would all be worth it. We like finding novel solutions to interesting problems, so understanding the financial side of the equation was the last step of our evaluation. Would Chia farming make financial sense for Backblaze?
Farming Seemed Like It Could Be Lucrative…
The prospect of over $1M/month in income certainly caught our attention, especially because we thought we could feasibly do it “for free,” or at least without the kind of upfront investment in HDDs a typical Chia farmer would have to lay out to farm at scale. But then we came to our analysis of monetization.
Our Monetization and Cost Analysis for Farming Chia
Colin Weld, one of our software engineers, had done some analysis on his own when Chia first gained attention. He built on that analysis to calculate the amount of farming income we could make per week over time with a fixed amount of storage.
Our assumptions for the purposes of this analysis:
150PB of the buffer would be utilized.
The value of the coin is constant. (In reality, the value of the coin opened at $584.60 on June 8, 2021, when we ran the experiments. In the time since, it has dipped as low as $205.73 before increasing to $278.59 at the time of publishing.)
When we ran the calculations, the total Network space appeared to increase at a rate of 33% every week.
We estimated income in week one was 75% of the week before, with the percentage decreasing exponentially over time.
When we ran the calculations, the income per week on 150PB of storage was $250,000.
We assumed zero costs for the purposes of this experiment.
Assuming Exponential Growth of the Chia Netspace
If the Chia Netspace continued to grow at an exponential rate, our farming income per week would be effectively zero after 16 weeks. In the time since we ran the experiment, the total Chia netspace has continued to grow, but at a slightly slower rate.
Total Chia Netspace April 7, 2021–July 5, 2021
Source: Chiaexplorer.com.
For kicks, we also ran the analysis assuming a constant rate of growth. In this model, we assume a constant growth rate of five exabytes each week.
Assuming Constant Growth of the Chia Netspace
Even assuming constant growth, our farming income per week would continue to decrease, and this doesn’t account for our costs.
And Farming Wasn’t Going to Be Free
To quickly understand what costs would look like, we used our standard pricing of $5/TB/month as our effective “cost” as it factors in our cost of goods sold, overheard, and the additional work this effort would require. At $5/TB/month, 150PB costs $175,000 per week. Assuming exponential growth, our costs would exceed total expected income if we started farming any later than seven weeks out from when we ran the analysis. Assuming constant growth, costs would exceed total expected income around week 28.
A Word on the Network Price
In our experiments, we assumed the value of the coin was constant, which is obviously false. There’s certainly a point where the value of the coin would make farming theoretically profitable, but the volatility of the market means we can’t predict if it will stay profitable. The value of the coin and thus the profitability of farming could change arbitrarily from day to day. It’s also unlikely that the coin would increase in value without the triggering simultaneous growth of the Netspace, thus negating any gains from the increase in value given our fixed farming capacity. From the beginning, we never intended to farm Chia in a speculative fashion, so we never considered a possible value of the coin that would make it worth it to farm temporarily and ignore the volatility.
Chia Network Price May 3, 2021–July 5, 2021
Source: Coinmarketcap.com.
Should We Farm Chia? Our Decision and Why
Ultimately, we decided not to farm Chia. The cons outweighed the pros for us:
We wouldn’t reap the rewards the calculators told us we could because the calculators give a point-in-time prediction. The amount per week you could stand to make is true—for that week. Today, the Chia Calculator predicts we would only make around $400 per month.
While it would have been a fun experiment, figuring out how to plot Chia at speed and scale would have taken time we didn’t have if we expected it to be profitable.
We assume the total Chia Netspace will continue to grow even if it grows at a slower rate. As the Netspace grows, your chances of winning go down unless you can keep growing your plots as fast as the whole Network is growing. Even if we dedicated our whole business to it, there would come a point where we would not keep up because we have a fixed amount of storage to dedicate to farming while maintaining a non-speculative position.
It would usurp resources we didn’t want to devote. We’d have to dedicate part of our operation to manage the process of farming on the drives without affecting core operations.
If we farmed it using our B2 Native API to write to our live buffer, we’d risk losing plots if we had to overwrite them when demand spiked.
Finally, cryptocurrency is a polarizing topic. The lively debate among our team members sparked the idea for this post. Our team holds strong opinions about the direction we take, and rightfully so—we value open communication as well as unconventional opinions both for and against proposed directions. Some brought strong arguments against participation in the cryptocurrency market even as they indulged in the analysis along the way. In the end, along with the operational challenges and disappointing financials, farming Chia was not the right choice for us.
The experiment wasn’t all for nothing though. We still think it would be great to find a way to make our storage buffer more profitable, and this exercise sparked some other interesting ideas for doing that in a more sustainable way that we’re excited to explore.
Our Chia Conclusion… For Now
For now, our buffer will remain a buffer—our metaphorical fields devoid of rows upon rows of Chia. Farming Chia didn’t make sense for us, but we love watching people experiment with storage. We’re excited to see what folks do with our experimental solution for farming Chia on Backblaze B2 and to watch what happens in the market. If the value of Chia coin spikes and farming plots on B2 Cloud Storage allows farmers to scale their plots infinitely, all the better. In the meantime, we’ll put our farming tools away and focus on making that storage astonishingly easy.
Afterword: The Future of Chia
This exercise begs the question: Should anyone farm Chia? That’s a decision everyone has to make for themselves. But, as our analysis suggests, unless you can continue to grow your plots, there will come a time when it’s no longer profitable. That may not matter to some—if you believe in Chia and think it will increase in value and be profitable again at some point in the future, holding on to your plots may be worth it.
How Pooling Could Help
On the plus side, pooling technology could be a boon for smaller farmers. The Chia Network recently announced pooling functionality for all farmers. Much like the office lottery, farmers group their plots for a share of challenge rewards. For folks who missed the first wave of plotting, this approach offers a way to greatly increase their chances of winning a challenge, even if it does mean a diminished share of the winnings.
The Wastefulness Questions
Profitability aside, cryptocurrency coins are a massive drain on the environment. Coins that use proof of space and time like Chia are billed as a greener alternative. There’s an argument to be made that Chia could drive greater utilization of otherwise unused HDD space, but it still leads to an increase of e-waste in the form of burned out SSD drives.
Coins based on different algorithms might hold some promise for being more environmentally friendly—for example, proof of stake algorithms. You don’t need proof of space (lots or storage) or proof of work (lots of power), you just need a portion of money (a stake) in the system. Ethereum has been working on a transition to proof of stake, but it will take more time and testing—something to keep an eye on if you’re interested in the crypto market. As in everything crypto, we’re in the early days and the only thing we can count on is change, unpredictability, and the monetary value of anything Elon Musk Tweets about.
In September of 2019, we celebrated the 10-year anniversary of open-sourcing the design of our beloved Storage Pods. In that post, we contemplated the next generation Backblaze Storage Pod and outlined some of the criteria we’d be considering as we moved forward with Storage Pod 7.0 or perhaps a third-party vendor.
Since that time, the supply chain for the commodity parts we use continues to reinvent itself, the practice of just-in-time inventory is being questioned, the marketplace for high-density storage servers continues to mature, and the continuing cost effectiveness of scaling the manufacturing and assembly of Storage Pods has proved elusive. A lot has changed.
The Next Storage Pod
As we plan for the next 10 years of providing our customers with astonishingly easy to use cloud storage at a fair price, we need to consider all of these points and more. Follow along as we step through our thought process and let you know what we’re thinking—after all, it’s your data we are storing, and you have every right to know how we plan to do it.
Storage Pod Realities
You just have to look at the bill of materials for Storage Pod 6.0 to know that we use commercially available parts wherever possible. Each Storage Pod has 25 different parts from 15 different manufacturers/vendors, plus the red chassis, and, of course, the hard drives. That’s a trivial number of parts and vendors for a hardware company, but stating the obvious, Backblaze is a software company.
Still, each month we currently build 60 or so new Storage Pods. So, each month we’d need 60 CPUs, 720 SATA cables, 120 power supplies, and so on. Depending on the part, we could order it online or from a distributor or directly from the manufacturer. Even before COVID-19 we found ourselves dealing with parts that would stock out or be discontinued. For example, since Storage Pod 6.0 was introduced, we’ve had three different power supply models be discontinued.
For most of the parts, we actively try to qualify multiple vendors/models whenever we can. But this can lead to building Storage Pods that have different performance characteristics (e.g. different CPUs, different motherboards, and even different hard drives). When you arrange 20 Storage Pods into a Backblaze Vault, you’d like to have 20 systems that are the same to optimize performance. For standard parts like screws, you can typically find multiple sources, but for a unique part like the chassis, you have to arrange an alternate manufacturer.
With COVID-19, the supply chain was very hard to navigate to procure the various components of a Storage Pod. It was normal for purchase orders to be cancelled, items to stock out, shipping dates to slip, and even prices to be renegotiated on the fly. Our procurement team was on top of this from the beginning, and we got the parts we needed. Still, it was a challenge as many sources were limiting capacity and shipping nearly everything they had to their larger customers like Dell and Supermicro, who were first in line.
Supply chain logistics aren’t getting less interesting.
Getting Storage Pods Built
When we first introduced Storage Pods, we were the only ones who built them. We would have the chassis constructed and painted, then we’d order all the parts and assemble the units at our data center. We built the first 20 or so this way. At that point, we decided to outsource the assembly process to a contract manufacturer. They would have a sheet metal fabricator construct and paint the chassis, and the contract manufacturer would order and install all the parts. The complete Storage Pod was then shipped to us for testing.
Over the course of the last 12 years, we’ve had multiple contract manufacturers. Why? There are several reasons, but they start with the fact that building 20, 40, or even 60 Storage Pods a month is not a lot of work for most contract manufacturers—perhaps five days a month at most. If they dedicate a line to Storage Pods, that’s a lot of dead time for the line. Yet, Storage Pod assembly doesn’t lend itself to being flexed into a line very well, as the Storage Pods are bulky and the assembly process is fairly linear versus modular.
In addition, we asked the contract manufacturers to acquire and manage the Storage Pod parts. For a five-day-a-month project, their preferred process is to have enough parts on hand for each monthly run. But we liked to buy in bulk to lower our cost, and some parts like backplanes had high minimum order quantities. This meant someone had to hold inventory. Over time, we took on more and more of this process, until we were ordering all the parts and having them shipped to the contract manufacturer monthly to be assembled. It didn’t end there.
As noted above, when the COVID-19 lockdown started, supply chain and assembly processes were hard to navigate. As a consequence, we started directing some of the fabricated Storage Pod chassis to be sent to us for assembly and testing. This hybrid assembly model got us back in the game of assembling Storage Pods—we had gone full circle. Yes, we are control freaks when it comes to our Storage Pods. That was a good thing when we were the only game in town, but a lot has changed.
The Marketplace Catches Up
As we pointed out in the 10-year anniversary Storage Pod post, there are plenty of other companies that are making high-density storage servers like our Storage Pod. At the time of that post, the per unit cost was still too high. That’s changed, and today high-density storage servers are generally cost competitive. But unit cost is only part of the picture as some of the manufacturers love to bundle services into the final storage server you receive. Some services are expected, like maintenance coverage, while others—like the requirement to only buy hard drives from them at a substantial markup—are non-starters. Still, over the next 10 years, we need to ensure we have the ability to scale our data centers worldwide and to be able to maintain the systems within. At the same time, we need to ensure that the systems are operational and available to meet or exceed our expectations and those of our customers, as well.
The Amsterdam Data Center
As we contemplated opening our data center in Amsterdam, we had a choice to make: use Storage Pods or use storage servers from another vendor. We considered shipping the 150-pound Storage Pods to Amsterdam or building them there as options. Both were possible, but each had their own huge set of financial and logistical hurdles along the way. The most straightforward path to get storage servers to the Amsterdam data center turned out to be Dell.
The process started by testing out multiple storage server vendors in our Phoenix data center. There is an entire testing process we have in place, which we’ll cover in another post, but we can summarize by saying the winning platform needed to be at least as performant and stable as our Storage Pods. Dell was the winner and from there we ordered two Backblaze Vaults worth of Dell servers for the Amsterdam data center.
The servers were installed, our data center techs were trained, repair metrics were established and tracked, and the systems went live. Since that time, we added another six Backblaze Vaults worth of servers. Overall, it has been a positive experience for everyone involved—not perfect, but filled with learnings we can apply going forward.
By the way, Dell was kind enough to make red Backblaze bezels for us, which we install on each of the quasi-Storage Pods. They charge us extra for them, of course, but some things are just worth it.
Faceplate on the quasi-Storage Pod.
Lessons Learned
The past couple of years, including COVID, have taught us a number of lessons we can take forward:
We can use third-party storage servers to reliably deliver our cloud storage services to our customers.
We don’t have to do everything. We can work with those vendors to ensure the equipment is maintained and serviced in a timely manner.
We deepened our appreciation of having multiple sources/vendors for the hardware we use.
We can use multiple third-party vendors to scale quickly, even if storage demand temporarily outpaces our forecasts.
Those points, taken together, have opened the door to using storage servers from multiple vendors. When we built our own Storage Pods, we achieved our cost savings from innovation and the use of commodity parts. We were competing against ourselves to lower costs. By moving forward with non-Backblaze storage servers, we will have the opportunity for the marketplace to compete for our business.
Are Storage Pods Dead?
Right after we introduced Storage Pod 1.0 to the world, we had to make a decision as to whether or not to make and sell Storage Pods in addition to our cloud-based services. We did make and sell a few Storage Pods—we needed the money—but we eventually chose software. We also decided to make our software hardware-agnostic. We could run on any reasonably standard storage server, so now that storage server vendors are delivering cost-competitive systems, we can use them with little worry.
So the question is: Will there ever be a Storage Pod 7.0 and beyond? We want to say yes. We’re still control freaks at heart, meaning we’ll want to make sure we can make our own storage servers so we are not at the mercy of “Big Server Inc.” In addition, we do see ourselves continuing to invest in the platform so we can take advantage of and potentially create new, yet practical ideas in the space (Storage Pod X anyone?). So, no, we don’t think Storage Pods are dead, they’ll just have a diverse group of storage server friends to work with.
Storage Pod Fun
Over the years we had some fun with our Storage Pods. Here are a few of our favorites.
Last week—in response to the hard drive shortage driven by Chia’s astronomical netspace growth—Backblaze introduced an experimental solution to allow farming of Chia plots stored in B2 Cloud Storage. Lots of folks have been reading it, and we remain fascinated by the up-and-down prospects of Chia.
Today’s post digs into the story behind one cryptocurrency startup that also aims to help Chia farmers enter this emerging market at scale: Plottair.
Crypto-entrepreneurs and Plottair Co-founders Maran Hidskes and Sinisa Stjepanovic approached us about building a SaaS service with a storage-heavy use case. Specifically, they wanted to use Backblaze B2 as part of a new Chia farming venture. They agreed to share their take on this latest trend in crypto and offer some insight into how they intend to use B2 Cloud Storage for their startup—we’re sharing some of what they told us here.
The conversation started with a bit of context around Chia’s roots (if you’ll excuse the pun) to set the stage for what Plottair is doing and why.
Ch- Ch- Ch- Ching:
A Greener Blockchain Transaction Platform
The Chia project was founded in August 2017 by Bram Cohen, the inventor of the BitTorrent protocol. Cohen was frustrated by the environmental impact of existing cryptocurrencies, so he developed a less wasteful scheme.1 Rather than using energy-intensive compute resources, with Chia, customers use free disk space to store calculations and use this data on the network to obtain a chance to win block rewards.
“This wasn’t an original idea,” Sinisa explained to us. “There were earlier coins that used proof of space—for example, Burstcoin—but Cohen improved it. He added proof of time and corrected issues with the consensus mechanism.”
The Basics of How Chia Works
In Chia, “farmers” create plots much like bingo cards with millions of digits, and the cards are stored locally, using around 110GB each. The network will occasionally ask a farmer whether their plots contain a certain number on their bingo cards, and if they possess it, they win a block reward: Chia coins.
There are two ways to play the Chia market:
Currency speculation similar to Bitcoin and others.
Farming plots, which could result in block rewards. Chia is trading at $416.79 as of this posting, and a block reward consists of two Chia coins.
While Chia has worked around the CPU intensive proof of work required for Bitcoin, it is very storage intensive (the data storage capacity for Chia in network space is already closing in on 25EiB), as farmers need to harvest many plots to win rewards. Rather than mining coins by dedicating large amounts of parallel processing power to the task, Chia simply requires storage—a lot of it, if you want the best chance of winning.
Total Chia netspace as of posting. That’s a lot of plots. Credit: Chia Explorer.
Plottair Finds a Market in Chia Farmers
Maran and Sinisa recognized that Chia farmers face two key challenges:
Obtaining and maintaining the computing power to generate plots.
Buying and managing the capacity to store the plots in secure, durable, highly available storage systems.
Fast processing power and low latency, high throughput NVMe storage is needed to generate plots, and most Chia farmers don’t have that kind of hardware. Sinisa had experimented with farming plots himself, and Maran owned a Plex hosting service—Bytesized Hosting. So Maran had the kind of hardware needed to speed up the process.
The two friends realized there would be plenty of other farmers looking for the same capability, and Plottair was born: A fully automated plotting service with optional cloud harvesting and multi-region download locations, aiming to provide the best support and download retention in the business.
And yet, while Maran’s servers were ideal for generating the plots quickly, they needed storage to house the plots between generation and download. With their plotting capacity at 50TB per day and a 30-day download window for customers, this was not a small issue.
Plottair began by hosting the plots in its own data centers, but identified three challenges:
1. They couldn’t scale fast enough.2. Managing a rapidly growing data center—racking up servers, ensuring connectivity, and having enough switches—was going to get in the way of their product focus.3. They needed to provide farmers with an easy way to download plots.
For all these needs, they sought out a cloud storage provider to partner with for holding plots.
Growing Plottair With Backblaze B2 Cloud Storage
Prior to finding Backblaze, Plottair engaged another cloud provider to host plots. After getting started, Plottair experienced some anomalies with users behavior in terms of downloads, and the provider froze the customer data without sharing any information that would have enabled a root cause analysis.
“They froze hundreds and hundreds of terabytes of my customers’ data, and then stonewalled me,” Maran complained. “They weren’t willing to share what caused the event.”
It was a real horror story—before the company would build with another partner, they needed to know they had support through the inevitable hiccups of launching a new business in uncharted territory. After the debacle, they reached out. “We were super happy to be able to see and speak to real humans when we reached out to Backblaze,” Maran said. Sinisa added, “We were looking for a partnership where both parties respect each other’s business. Calling off the entire service when something goes wrong? That’s a very bad look to our customers.”
Where Backblaze B2 Fits in Plottair’s Workflow
When purchasing plots, farmers give their farming keys to Plottair and select a location where the plots should be stored—in the Backblaze U.S. West or European regions. A call goes out to one of Plottair’s plotting servers that has free availability, and it starts plotting. This takes about six to eight hours per plot.
When the plot is finished, it gets uploaded from the plotting server to the appropriate Backblaze location, and the customer is notified that the plot is ready to download via Plottair’s customer portal. In the portal, farmers can view all plot orders and their statuses, so they know when they can start downloading. Plottair optionally allows customers to farm these plots in the cloud.
How Backblaze B2 Meets the Needs of Blockchain Workloads
In addition to gaining a working partnership, the biggest strength Backblaze B2 brings to the Plottair venture is the ability to scale up to any size. “I don’t have to worry if I’ll have enough storage if I get a petabyte order,” Maran said.
Plottair has the ability to upload vast amounts of data at scale and let their users directly access it and use it in real-time. This enables Plottair to use the space they need to serve the Chia farming market if it booms and, with a pay-as-you-go model, scale back if it busts. “That’s the dream,” Maran said. “To have something that scales on every facet. Right now, Backblaze is there for us for our storage needs.”
Backblaze B2: Storage for Emerging Services
Whatever happens with cryptocurrencies, storage-intensive cloud services are becoming more and more common. Many new SaaS applications with storage-heavy workloads—companies like streaming media services or gaming platforms—are either migrating over from AWS or other legacy providers, or building their infrastructure with Backblaze B2.
Maran is also considering Backblaze B2 for other blockchain oriented workloads. In the near term, Maran and his team are looking to “harvest” the Chia plots as a service using Backblaze B2. Harvesting involves reading the large number sequences for a match. This will enable Chia farmers to download only a fraction of the plot data, significantly improving their experience.
As Plottair grows its product offerings in cryptocurrencies and other blockchain-oriented use cases and considers many additional functions, we’ll be excited to report on new development. For now, we’ll simply focus on how the Chia market and their “acreage” might grow.
Blockchain and Cryptocurrency: A Short History
Financial institutions and a growing number of firms across industries are using distributed ledger technology based on blockchain as a secure and transparent way to digitally track the ownership of assets. Bitcoin was one of the first applications built on top of blockchain. Bitcoin and its underlying blockchain technology are viewed by many as the leading edge of a transformative evolution of money, finance, commerce, and society itself. The total value of all Bitcoin now in existence is over half a trillion dollars.
Bitcoin and most other cryptocurrencies use a system in which currency is created or “mined” using computers to solve mathematical puzzles. These are known as “proof of work” systems—solving the puzzle is proof that your computer has done a certain amount of work to provide network authentication.
One of Bitcoin’s core tenets is decentralization, but specialized hardware and cheap electricity have become far better at proof of work calculations than general purpose CPUs. This development has weakened decentralization as the specialized “mining” hardware is increasingly owned and operated by just a few large entities in huge, purpose-built data centers located near inexpensive electricity. This centralization has served to lower trust and raise difficult issues regarding electricity consumption, e-waste, carbon generation, and global warming. By some estimates, Bitcoin consumes more electricity than whole countries. In response, new blockchain currencies have emerged that seek to be more sustainable.
1Editor’s note: At this point, it’s unclear whether Chia is on the whole greener than “proof of work” cryptos. Some are looking into it, and we’ll be exploring the question too, but we would be interested to learn anything else our community has learned. When the energy and physical waste that goes into manufacturing hard drives is factored into the overall equation, given the exceptional amount of demand that Chia has created for drives, will it still be able to claim the “green crypto” name?
In most industries, one lost file isn’t a big deal. If you have good backups, you just have to find it, restore it, and move on—business as usual. But in the business of streaming media, one lost file can cause playback issues, compromising the customer experience.
Kanopy, a video streaming platform serving more than 4,000 libraries and 45 million library patrons worldwide, previously used an all-in-one video processing, storage, and delivery provider to manage their media, but reliability became an issue after missing files led to service disruptions.
We spoke with Kanopy’s Chief Technology Officer, Dave Barney, and Lead Video Software Engineer, Pierre-Antoine Tible, to understand how they restructured their tech stack to achieve reliability and three times more redundancy with no increase in cost.
Kanopy: Like Netflix for Libraries
Describing Kanopy as “Netflix for libraries” is an accurate comparison until you consider the number of videos they offer: Kanopy has 25,000+ titles under management, many thousands more than Netflix. Founded in 2008, Kanopy pursued a blue ocean market in academic and, later, public libraries rather than competing with Netflix. The libraries pay for the service, offering patrons free access to films that can’t be found anywhere else in the world.
Kanopy provides thoughtful entertainment that bridges cultural boundaries, sparks discussion, and expands worldviews.
Streaming Media Demands Reliability
In order for a film to be streamed without delays or buffering, it must first be transcoded—broken up into smaller, compressed files known as “chunks.” A feature-length film may translate to thousands of five to 10-second chunks, and losing just one can cause playback issues that disrupt the viewing experience. Pierre-Antoine described a number of reliability obstacles Kanopy faced with their legacy provider:
The provider lost chunks, disabling HD streaming.
The CDN said the data was there—but user complaints made it clear it wasn’t.
Finding source files and re-transcoding them was costly in both time and resources.
The provider didn’t back up data. If the file couldn’t be located in primary storage, it was gone.
Preparing for a Cloud to Cloud Migration
For a video streaming service of Kanopy’s scale, a poor user experience was not acceptable. Nor was operating without a solid plan for backups. To increase reliability and redundancy, they took steps to restructure their tech stack:
First, Kanopy moved their data out of their legacy provider and made it S3 compatible. Their legacy provider used its own storage type, so Pierre-Antoine and Kanopy’s development team wrote a script themselves to move the data to AWS, where they planned to set up their video processing infrastructure.
Next, they researched a few solutions for origin storage, including Backblaze B2 Cloud Storage and IBM. Kanopy streams out 15,000+ titles each month, which would incur massive egress fees through Amazon S3, so it was never an option. Both Backblaze B2 and IBM offered an S3 compatible API, so the data would have been easy to move, but using IBM for storage meant implementing a CDN Kanopy didn’t have experience with.
Then, they ran a proof of concept. Backblaze proved more reliable and gave them the ability to use their preferred CDN, Cloudflare, to continue delivering content around the globe.
Finally, they completed the migration of production data. They moved data from Amazon S3 to Backblaze B2 using Backblaze’s Cloud to Cloud Migration service, moving 150TB in less than three days.
Where’s the popcorn? The Kanopy team takes a break.
Building a Tech Stack for Streaming Media
Kanopy’s vendor-agnostic, multi-cloud tech stack provides them the flexibility to use integrated, best-of-breed providers. Their new stack includes:
IBM Aspera to receive videos from contract suppliers like Paramount or HBO.
AWS for transcoding and encryption and Deep Glacier for redundant backups.
Flexify.IO for ongoing data transfer.
Backblaze B2 for origin storage.
Cloudflare for CDN and edge computing.
The Benefits of a Multi-cloud, Vendor-agnostic Tech Stack
The new stack offers Kanopy a number of benefits versus their all-in-one provider:
Since Backblaze is already configured with Cloudflare, data stored on Backblaze B2 automatically feeds into Cloudflare’s CDN. This allows content to live in Backblaze B2, yet be delivered with Cloudflare’s low latency and high speed.
Benefitting from the Bandwidth Alliance, Kanopy pays $0 in egress fees to transfer data from Backblaze to Cloudflare. The Bandwidth Alliance is a group of cloud and networking companies that discount or waive data transfer fees for shared customers.
Egress savings coupled with Backblaze B2’s transparent pricing allowed Kanopy to achieve redundancy at the same cost as their legacy provider.
Scaling a Streaming Media Platform With Backblaze B2
Though reliability was a main driver in Kanopy’s efforts to overhaul their tech stack, looking forward, Dave sees their new system enabling Kanopy to scale even further. “We’re rapidly accelerating the amount of content we onboard. Had reliability not become an issue, cost containment very quickly would have. Backblaze and the Bandwidth Alliance helped us attain both,” Dave attested.
“We’re rapidly accelerating the amount of content we onboard. Had reliability not become an issue, cost containment very quickly would have. Backblaze and the Bandwidth Alliance helped us attain both.” —Dave Barney, Chief Technology Officer, Kanopy
Anyone that pays attention to the hard drive market as closely as Backblaze does already knows all about the rapid rise in popularity of Chia—the “green” alternative to Bitcoin—and the effect it’s having on global drive supplies. If you haven’t heard about Chia, check out the short note below for more info. But this post is geared for the many Chia farmers out there who’ve already delved into farming and are now facing empty shelves as they seek out storage solutions for their plots.
With this shortage in mind, our team set out to explore an experimental solution that would allow for farming of Chia plots stored in B2 Cloud Storage. We’re happy to announce that it is now possible for Chia farmers to store and farm their plots in Backblaze B2.
So if you’re looking to participate in the Chia sensation without spending a lot on hard-to-find, high-capacity hard drives, there is now an innovative way to get started with an affordable, scalable cloud solution.
Chia vs. Bitcoin: Chia is a new cryptocurrency that employs a proof-of-space algorithm. As opposed to the proof-of-work algorithm supporting Bitcoin—which is both CPU and energy intensive—Chia was developed to minimize energy consumption. The result is a storage intensive form of blockchain. If you’d like to learn more, we recommend going to the source.
The Keys to Winning Chia Challenges
Chia plots are not just lying idle. The Chia network regularly issues matching challenges and quality checks. The quality checks are important to succeed at, but the challenges—where one of every 512 plots is challenged every 10 minutes—are why you’re farming.
If one of your plots is selected for a match challenge, you need to fetch a “full proof” to collect a reward, which requires around 64 hard drive seeks and delivery of the full proof to the rest of the peer-to-peer network in less than 30 seconds, before Chia “time lords” move the blockchain further along.
This presents two problems that might keep you up at night if you’re trying to farm Chia:
Problem 1: Where to store plots at scale.
Given that the current estimated network space occupied by Chia plots is 20 exabytes (and growing exponentially!), chance dictates that just one of your plots will emerge as the winner once in about 96 years. It’s like waiting a lifetime for an ear of corn—not fun. So you want to have a lot of plots to improve your odds—but you need somewhere to keep them that you can afford and that can grow with your farming.
Problem 2: Administering the complexity of scaling storage.
If you solve the storage problem, then you also need a way to quickly and reliably make all of the plots available to be read and quickly presented to the network when you win a challenge. You’ll need to be able to administer that complexity every second of every day for as long as you want to be a farmer. If you wait 96 years for a single ear of corn, it would be a bummer to miss harvest day.
These are the keys to winning the match challenge: Attaining scale and capably administering it.
The Status Quo: Individual Chia Farmers Using HDDs for Storage
For a 7200 RPM HDD with an approximately 10ms read latency, getting a quality check or a full proof takes around 70ms per qualifying plot. Because the Chia kernel caches the first seven reads, the HDD only must perform the 64 seeks when issued a challenge.
If an 18TB drive—which can hold 166 plots at 108GB per plot (using k=32)—is lucky enough to contain a plot that is that magical “one in 512,” the HDD is reasonably fast in performing the necessary read operations, because Chia was designed to use HDDs for Plot Farming. But HDDs can only perform one of those operations at a time, so a desktop must perform the operations sequentially. Even if you’re using an SSD, you still must perform the operations in series. Again, this isn’t an issue for individual drives since HDDs and SSDs are able to perform the operations very quickly within the allotted time frame.
But, even for those lucky enough to find a supply of readily available 18TB drives that haven’t been marked up twice, providing storage for the number of plots a Chia Farmer needs to ensure a reasonable chance for success is going to be labor and capital intensive.
How to Use Cloud Storage to Scale Your Plots
Chia software was not designed to allow farming with public cloud object storage, and the first tests we ran on Chia plots stored in B2 Cloud Storage proved this out: taking minutes, not the 30 seconds necessary to pass the quality check in time. Unlike with a local storage solution, where quality check reads can be cached by the kernel, performance is degraded in a cloud storage setup to an extent that it affects users’ success rate of winning challenges.
Backblaze B2 Cloud Storage provides object storage, which stores data in discrete objects, negating the need for any nested or hierarchical file structure. This makes B2 Cloud Storage ideal for scaling and use as an origin store, but as a standalone product, object storage is not suited for storing Chia plots. Without caching optimizations to improve performance and a way to read plots concurrently, B2 Cloud Storage would not effectively serve the Chia farming use case. But B2 Cloud Storage is designed to take advantage of parallel operations, or threads, offering some advantages over a standard physical drive if set up correctly for this use case (cough* I wrote about threads here!cough*).
Our team thought it would be interesting to build a tool providing a Chia use case workaround for four compelling reasons:
First: Because the Backblaze Storage Cloud provides both of the keys for successful Chia farming: There is no provisioning necessary and Chia Farmers can upload new plots at speed and scale. The Backblaze Storage Cloud cares for nearly 500 billion files with exceptional durability and availability.
Second: The cost of storing Chia plots in Backblaze B2 is financially compelling at $5/TB/month. According to Chia Calculator, using B2 Cloud Storage to store plots would be profitable, depending on the network space growth rate and the current price of Chia coin.
Third: A Tiger Team of SEs and engineers, including myself, thought it would make for an interesting and useful (and fun) experiment.
Finally: The same team believed we could enable Chia farming of plots stored in B2 Cloud Storage by cracking the code of how to parallelize operations in Chia.
With this in mind, our Tiger Team set out to get to work. A tool to mount Backblaze B2 as a filesystem was necessary since Chia doesn’t natively support the Backblaze B2 Native or S3 Compatible APIs. After some testing, our team settled on B2_fuse since our engineers who would be working on this already had some familiarity with the source code.
After deciding on B2_fuse, our engineers added a prefetch algorithm to cache the reads to address the kernel issue mentioned above. This would aid performance, but with reads still carried out one at a time on HDD, there was room for additional improvement. Obviously performing operations in parallel would greatly grow the success rate, and after doing some digging one of our engineers found a PR (pull request) that added parallelized reads and had not yet been merged into the Chia project.
With the caching optimizations in B2_fuse and the added functionality of parallelized reads, the proof time for a Chia plot stored in B2 Cloud Storage was reduced to seconds. This provides for uploading Chia plots to Backblaze B2 and presenting them to the Chia network for farming without the need for an expensive server in a datacenter.
Our successful tests were carried out using a compute instance running in a US West region with a Backblaze B2 account that is also in the US West region. Give it a shot and you could be staring at a whole field of metaphorical crops—all ready for whenever the “one in 512” challenge arrives.
Because this support is experimental and the Backblaze team knows a lot of Chia Farmers will be excited to try it out, we ask that farmers limit their storage of Chia plots to 100 TB at this time, or contact our sales team to discuss anything larger.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
 backups immediately to your VMware/Hyper-V based environment, so businesses can get back online with minimal disruption or expense. Put simply, it’s an on-demand path to a rock solid disaster recovery plan that makes recovery planning accessible and appropriately provisioned for your business.