Secure MCP integrations for AWS DevOps Agent with Amazon Bedrock AgentCore

Post Syndicated from Lakshmi Kumkala original https://aws.amazon.com/blogs/devops/secure-mcp-integrations-for-aws-devops-agent-with-amazon-bedrock-agentcore/

When the agent can’t reach data you need during an incident investigation, you extend it with new tools. You also manage the security and observability overhead of each tool you add. As you connect more Model Context Protocol (MCP) tools to AWS DevOps Agent, your security team ends up tracking a separate authentication scheme, credential rotation schedule, and audit or revocation procedure for each one. This post shows how to extend AWS DevOps Agent with MCP tools securely, using Amazon Bedrock AgentCore, so that new tools can inherit consistent security, access control, private connectivity, and observability.

AWS DevOps Agent is an AI-powered, always-available operations teammate that autonomously investigates incidents, identifies root causes, and prevents future issues across AWS, multicloud, and on-premises environments. It correlates Amazon CloudWatch metrics, logs, traces, and deployment history to produce root-cause analyses in minutes instead of hours. In Announcing General Availability of AWS DevOps Agent, AWS reported results from customers and partners who used AWS DevOps Agent in preview. They saw up to 75 percent lower mean time to resolution (MTTR), 80 percent faster investigations, and 94 percent root-cause accuracy.

By default, AWS DevOps Agent integrates with a broad set of observability, source control, continuous integration and continuous delivery (CI/CD), ticketing, and collaboration services. Real-world operational environments often extend further: proprietary configuration management databases (CMDBs), internal runbook APIs, application logs in OpenSearch, custom deployment tracking systems, or self-hosted tools behind private networks. When you need data from a source without a native integration, you can use MCP tools to give the agent a standardized way to call external services during an investigation.

You will learn when an MCP tool is the right answer, where to host it, how to connect it to AWS DevOps Agent, and how AgentCore Gateway, a capability of Amazon Bedrock AgentCore, provides a unified management layer for security, policy, and observability.

Where MCP tools fit in the incident lifecycle

Before examining tool infrastructure, it helps to see where MCP tools enter the picture. When your Amazon CloudWatch alarms, ServiceNow tickets, or PagerDuty alerts trigger an incident, AWS DevOps Agent begins an autonomous investigation. The following diagram shows where MCP tools extend that investigation beyond the agent’s native integrations.
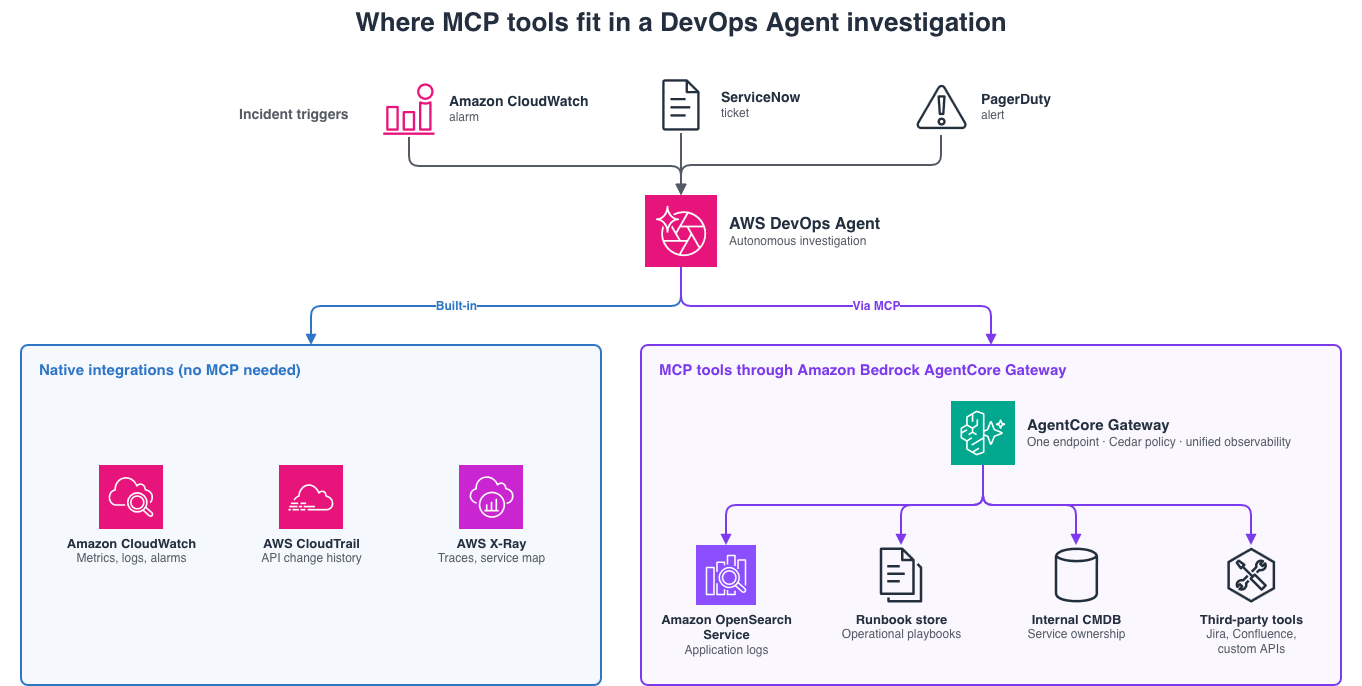
Flow diagram showing an incident triggering an AWS DevOps Agent investigation, with MCP tools extending the investigation to data sources beyond the native integrations of the agent.

Figure 1: MCP tools extend the investigation reach of AWS DevOps Agent beyond its native and built-in integrations

These tools can connect to internal operational tools, third-party platforms, on-premises systems, or any custom data source you want to expose to an agent space. AWS DevOps Agent provides logging and the ability to disconnect any MCP server from the console, but you configure authentication, rotate credentials, and maintain the audit trail for each server. As the number of MCP servers grows, managing them independently creates compounding overhead: separate credential lifecycles, no cross-tool policy enforcement, and no unified view for observability across all tools.

AgentCore Gateway helps reduce this per-tool overhead. The agent connects to one endpoint, and tools behind that endpoint share the same security, policy, and observability configuration.

For more on triggering investigations automatically, see Trigger DevOps Agent from CloudWatch Alarms & Amazon EventBridge and Automating DevOps Agent from Incident Detection and Response alarms.

When to extend AWS DevOps Agent with MCP servers

Use this decision framework to choose between a native integration, an existing MCP server, and building a custom MCP server when you need a new data source or workflow.
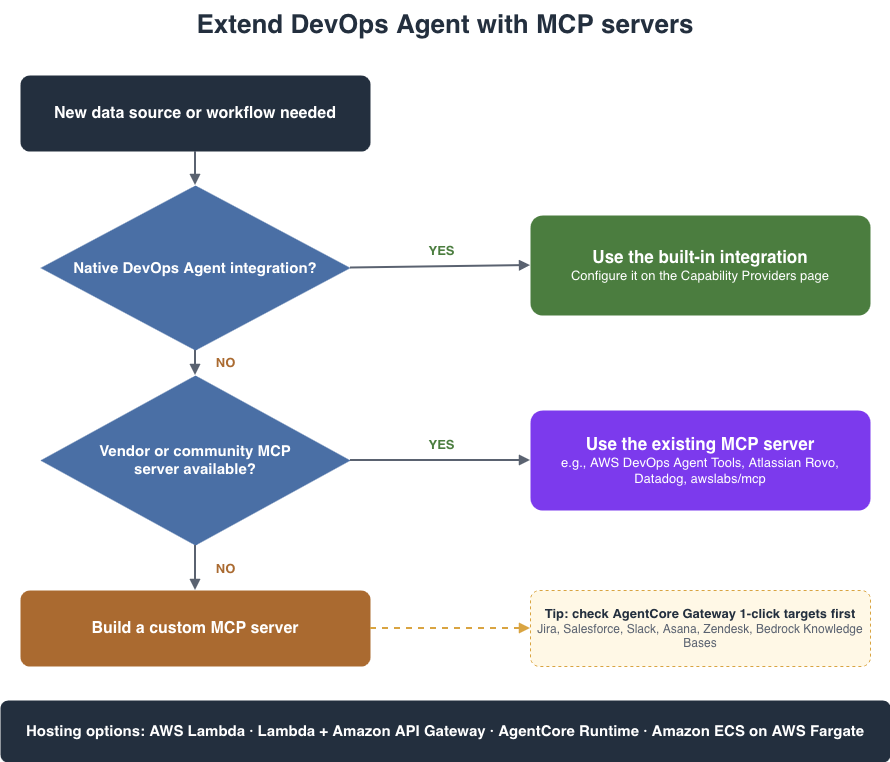
Decision framework flowchart for choosing between a native integration, an existing vendor MCP server, and building a custom MCP server.

Figure 2: Decision framework for extending AWS DevOps Agent: native integration, existing MCP server, or custom MCP server

Start with what AWS DevOps Agent already covers. Before building anything, check the native capability list on the Capability Providers page. These integrations need no custom server to build or host. AWS DevOps Agent Tools catalogs additional MCP servers built for use with the agent. It is also worth browsing the AWS DevOps Agent ACP/MCP samples repository for reference implementations, and awslabs/mcp for AWS-published open source MCP servers such as the Amazon Managed Service for Prometheus MCP server and the Amazon Elastic Kubernetes Service (Amazon EKS) MCP server.

If a source is not natively covered, check whether a vendor already publishes an MCP server before building your own. Many do. For example, Atlassian’s Rovo MCP Server covers Jira, Confluence, Jira Service Management, and Bitbucket, and vendors such as Datadog and PagerDuty publish official servers.

Build a custom MCP tool when your source does not fall into any of these categories. The most common scenarios are:

  • Logs that need domain-specific parsing. AWS DevOps Agent can read log files in Amazon Simple Storage Service (Amazon S3) and query them with Amazon Athena once you grant it access. To do this, add the S3 read and Athena query permissions to its role as an inline policy, scoped to the buckets it needs. For more information, see Extending permissions beyond the default. For high-volume formats such as Application Load Balancer (ALB) access logs and VPC Flow Logs, a custom tool is often the better fit. An AWS Lambda-based MCP tool that parses and pre-filters these logs gives the agent the context to correlate a 502 spike with a specific backend failure. Application logs in Amazon OpenSearch Service follow the same pattern, because they need domain-specific language (DSL) query logic rather than raw document retrieval. For reference patterns, see Six Patterns for Connecting Amazon OpenSearch Service Logs to AWS DevOps Agent.
  • Internal operational tools. Runbook APIs, proprietary CMDBs, service ownership registries, and custom deployment tracking systems are not reachable through any native integration. An MCP tool wraps the internal API and exposes it as a callable tool during investigations.
  • On-premises or other-cloud telemetry. Data from on-premises monitoring systems or GCP infrastructure that is not captured in native AWS services requires tools that can reach those environments. For network-specific patterns, see Automated network incident response with AWS DevOps Agent.

AgentCore Gateway also provides one-click integrations for tools such as Jira, Salesforce, Slack, Asana, and Zendesk, as well as native support for Amazon Bedrock Knowledge Bases as a Gateway target. If your tool is available as a one-click target, you can skip building a custom MCP server and register it directly on the Gateway, which you then connect to AWS DevOps Agent as an MCP server through the agent’s capabilities.

Where to host your custom MCP server

After you decide to build a custom MCP tool, you need to choose where it runs. The right choice depends on statefulness, latency tolerance, connection requirements, and how much infrastructure you want to manage. The following table compares the four most common hosting options.

Hosting option Best for Advantages Trade-offs
AWS Lambda (direct IAM invoke) Stateless, read-heavy tools that execute quickly, such as Amazon S3 log parsers, OpenSearch query wrappers, runbook search, and internal API or ticket lookups No infrastructure to manage, pay-per-invocation, and auto-scales to zero. AgentCore Gateway invokes Lambda directly through IAM, without needing the HTTP layer, which removes Amazon API Gateway latency for Gateway-connected tools 15-minute execution limit, cold-start latency on first invoke, and no persistent connections
AWS Lambda with Amazon API Gateway Shared tools used by multiple teams or systems, and tools that require request throttling or AWS WAF protection All Lambda benefits, plus HTTP-level controls such as throttling, WAF protection, custom domains, and per-caller access logging Added per-request latency, Amazon API Gateway per-request cost, and more configuration
Amazon Bedrock AgentCore runtime Teams who want zero-ops MCP hosting with native multi-turn session support No infrastructure to manage, built-in session isolation, native MCP protocol support, both stateless and stateful modes, and support for your own container image. Works with any MCP framework, including LangGraph, CrewAI, and Strands Agents Cold-start latency when a new session starts, and less control over the underlying compute than Amazon Elastic Container Service (Amazon ECS)
Amazon ECS on AWS Fargate Database query tools that maintain connection pools, and tools with expensive initialization or large in-memory caches No cold starts, persistent connections, and full control over the runtime environment Always-on cost even when idle, and container image management overhead

For hosting walkthroughs, see Connect API Gateway to AgentCore Gateway with MCP for the API Gateway pattern and Deploy MCP servers in Runtime for AgentCore runtime. The AgentCore runtime released in September 2026 reduces cold starts to about two seconds at p75 regardless of container image size.

As a rule of thumb, start with Lambda for most read-only tools, move to AgentCore runtime, a capability of Amazon Bedrock AgentCore, when you need multi-turn sessions or zero-ops hosting, and use Amazon ECS when you need persistent connections or large in-memory state.

Connecting MCP servers to AWS DevOps Agent

There are two ways to connect MCP servers to AWS DevOps Agent. The right choice depends on how many tools you have, whether tool access needs to be consistent across multiple accounts, and whether you need central policy enforcement. The following diagram compares a direct per-account connection with a single connection through AgentCore Gateway.
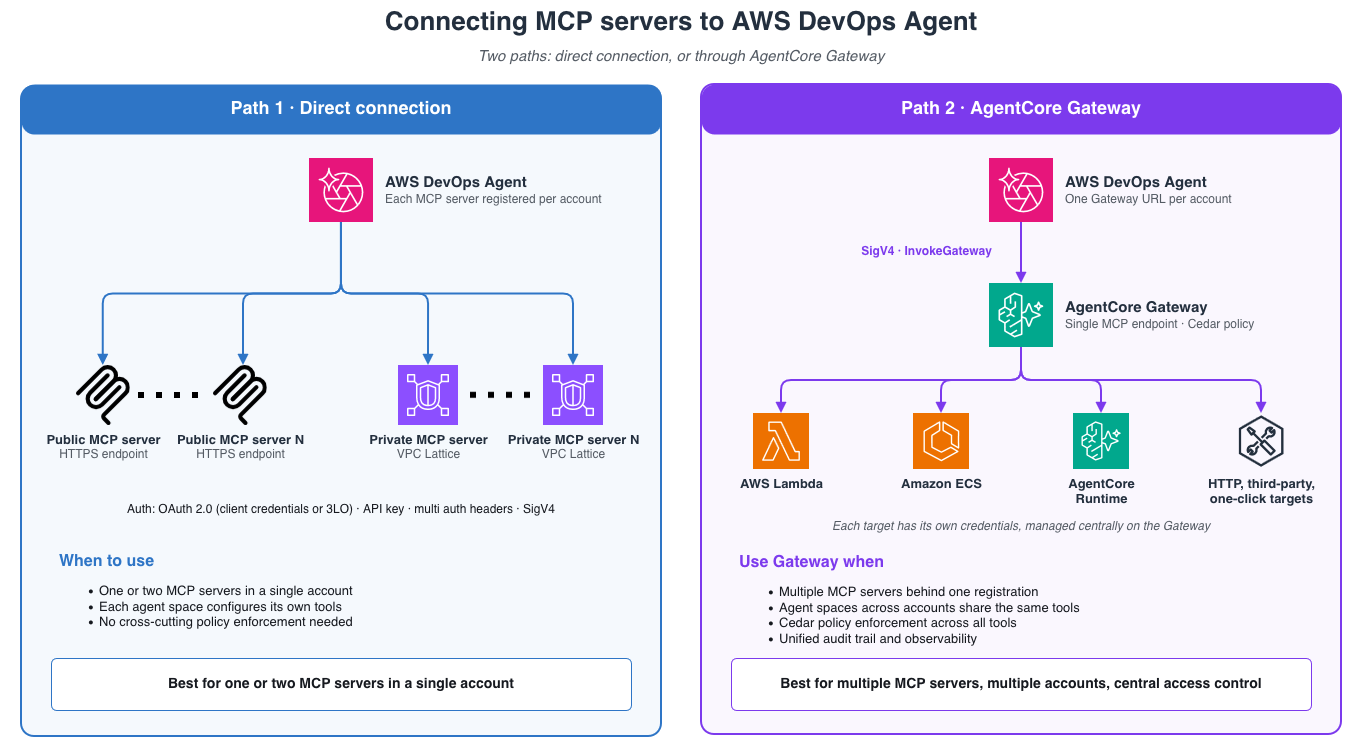
Comparison of two connection paths. Path 1, direct connection, where AWS DevOps Agent registers each public and private MCP server per account. Path 2, where a single AgentCore Gateway endpoint fronts multiple targets including AWS Lambda, Amazon ECS, AgentCore runtime, and HTTP or third-party one-click targets.

Figure 3: Connecting MCP servers to AWS DevOps Agent: direct connection compared to AgentCore Gateway

Path 1: Direct connection

With a direct connection, you register each MCP server at the AWS account level from the Capability Providers page. To register a server:

  1. On the Capability Providers page, register the MCP server once with its endpoint URL and authentication credentials.
  2. In each agent space’s Capabilities tab, select the registered MCP server and choose which specific tools to enable for that space.
  3. Classify each tool as read-only, mutating, or destructive so that AWS DevOps Agent applies the correct safety controls during investigations.

Your MCP server must implement the streamable HTTP transport protocol and support one of the following authentication methods:

  • OAuth 2.0 Client Credentials.
  • OAuth 3LO (three-legged OAuth).
  • API key or token-based authentication.
  • Multi-auth headers (up to three secrets sent in HTTP headers that you name).
  • AWS Signature Version 4 (SigV4).

AWS DevOps Agent supports private connections natively. When you register an MCP server, select Connect to endpoint using private connection and choose or create a private connection. AWS DevOps Agent uses Amazon VPC Lattice to route traffic to your private endpoint entirely over the AWS network, with no public endpoint needed. Private connections work with any integration that needs to reach a private endpoint, including self-hosted Grafana or Splunk instances and source control systems such as GitHub Enterprise Server and GitLab Self-Managed. For a detailed walkthrough, see Securely connect AWS DevOps Agent to private services in your VPCs.

Tool safety with directed actions

When you connect an MCP server, you classify each of its tools as read-only, mutating, or destructive. The console prompts you for each tool, and API or CLI registrations set this with toolDetails. Read-only tools run without operator approval. Mutating tools are available only after you enable directed actions on the agent space, and each call requires operator approval in chat. AWS DevOps Agent does not invoke tools classified as destructive. If you register a server through the API or CLI without classifying its tools, every tool defaults to read-only, so classify any tool that can change state. For more information, see Working with directed actions.

Limit prompt-injection exposure

Custom MCP servers can introduce additional prompt-injection risk. Allow only the tools each agent space needs, prefer read-only tools, and give each server’s credentials read-only access. For more information, see the security considerations in Connecting MCP Servers.

Path 2: Amazon Bedrock AgentCore Gateway

AgentCore Gateway is a fully managed service that provides a single, secure entry point for agentic traffic, connecting agents to tools, to other agents, and to models. Instead of registering each MCP server independently in the AWS DevOps Agent account, you register all of them as targets on the Gateway. AWS DevOps Agent registers the Gateway URL once at the account level, and all tools from all registered targets become available through that single registration.

Gateway also consolidates authentication. AWS DevOps Agent connects to a single Gateway endpoint with AWS SigV4. It signs requests with either a dedicated IAM role or, if you register without one, the IAM role of the AWS account associated with the agent space. Grant that role bedrock-agentcore:InvokeGateway, scoped to the Gateway ARN. You still configure per-target credentials on the Gateway, because each backend MCP server has its own authentication. But the Gateway manages those credentials centrally, handling token refresh, secure storage, and credential lifecycle in one place rather than scattering them across individual agent space registrations.

With Policy in Amazon Bedrock AgentCore, you can enforce Cedar rules across every tool behind the Gateway with a single policy, for example blocking any tool that writes to production resources regardless of which MCP server exposes it. Because AWS DevOps Agent already refuses tools classified as destructive, Gateway policy is most valuable as an independent backstop in case someone misclassifies a tool.

Gateway also provides a unified audit trail and built-in observability automatically, with no instrumentation code and no per-target logging configuration. Amazon CloudWatch Logs records every tool call, including tool name, caller identity, request arguments, response, latency, and status, across all registered targets in one log group. AWS X-Ray provides end-to-end distributed traces across the MCP client, Gateway, and Lambda or runtime layers. The CloudWatch generative AI observability dashboard reports per-tool metrics, including invocation count, error rate, and latency percentiles (p50, p90, and p99). These metrics appear regardless of whether the tool runs on Lambda, Amazon ECS, AgentCore runtime, or a third-party server.

Gateway can also route to private MCP servers through VPC Lattice egress. If you need private connectivity together with the authentication, policy, and observability capabilities of the Gateway, register the tool as a private Gateway target. For connectivity patterns, see Private connectivity patterns for AgentCore Gateway Targets. If you only need private connectivity for a single tool without central policy, a direct private connection requires less configuration.

You can also route native MCP integrations through Gateway. Some AWS DevOps Agent native capabilities, such as the Grafana integration, connect to external MCP servers (Grafana’s own MCP server, in this case). If you want unified policy enforcement, observability, and authentication across both your native MCP-based integrations and your custom MCP servers, you can route them through AgentCore Gateway as well. This gives you a single control plane regardless of whether the tool came from the Capability Providers page or a custom registration.

For more on extending Gateway with MCP servers, see Extending MCP support for AgentCore Gateway and Transform your MCP architecture: Unite MCP servers through AgentCore Gateway.

Choosing between direct connection and Gateway

Use a direct connection when you have one or two MCP servers in a single AWS account, when each agent space configures its own tool set manually, and when you do not need cross-cutting policy enforcement. Choose AgentCore Gateway when you have multiple MCP servers and want to manage them through a single registration, when agent spaces across multiple AWS accounts need to share the same tools, when you want one authentication configuration, when you need Cedar policy enforcement across all tools, or when you want a unified audit trail and built-in observability. For full instructions, see Connecting MCP Servers in the AWS DevOps Agent User Guide.

Connectivity options at a glance

This table maps common scenarios to the recommended connection approach.

Scenario Recommended approach
One or two MCP servers, single account Direct connection
Multiple MCP servers, single registration preferred AgentCore Gateway
Agent spaces across multiple AWS accounts sharing the same tools AgentCore Gateway
Private VPC tool, no central policy needed Direct connection with DevOps Agent private connection
Private VPC tool with Cedar policy or unified auth Gateway with VPC Lattice target
Cedar policy enforcement across all tools AgentCore Gateway
Unified audit trail across all MCP servers AgentCore Gateway

Managing tool access with Gateway targets and policy

Beyond choosing a connection path, Gateway gives you finer control over which tools an agent space can reach.

Keep the per-space tool ceiling in mind as you scope access: a single agent space can have at most 500 MCP tools on the allowlist across all of its MCP servers, and this limit is not adjustable. Scoping each space to only the tools it needs keeps you well under that ceiling. For the full list of limits, see AWS DevOps Agent quotas.

When AWS DevOps Agent connects to an MCP server, its tools appear on the agent space console, where an admin selects which tools to allow and classifies each one as read-only, mutating, or destructive. This workflow exists with or without Gateway.

Gateway adds a mechanism on top: separate targets per tool category. Register read-only tools and write or destructive tools as separate Gateway targets, then associate AWS DevOps Agent with only the read-only target. The write tools don’t appear in that agent space, because they are not in the target. For how to register targets, see Add targets to an existing AgentCore Gateway.

For example, if an MCP server exposes list_runbooks, get_runbook, search_runbooks, upload_runbook, and delete_runbook, register a target named readonly-runbook-tools with only the first three. Connect the production agent space to the readonly-runbook-tools target, and connect development and staging agent spaces to a target that exposes all five tools.

Even when tools are visible and enabled in an agent space, Gateway policy, which uses Cedar, can block execution. This is the enforcement boundary below the admin workflow, and it holds regardless of what an admin configures on the console, which helps guard against configuration mistakes. For more on Cedar policy patterns, see Secure AI agents with Policy in Amazon Bedrock AgentCore.

Conclusion

AWS DevOps Agent covers a broad set of AWS services and third-party tools by default. When investigations need to reach further, into OpenSearch, internal runbook APIs, proprietary CMDBs, or tools in private VPCs, MCP tools extend that reach.

For one or two tools in a single account, a direct connection with account-level registration is sufficient. The picture changes when MCP servers multiply, when agent spaces span multiple AWS accounts, or when security teams need consistent enforcement and a unified audit trail. AgentCore Gateway collapses that to one registration per account pointing to a single Gateway URL. You configure authentication once, enforce Cedar policies consistently, get built-in CloudWatch observability across your tools, and revoke access in one place instead of across each tool registration.

For more on what AWS DevOps Agent can do by default, see Announcing General Availability of AWS DevOps Agent, AWS DevOps Agent features, and Native Capabilities.

Get started

To try this pattern, register one read-only MCP server as an AgentCore Gateway target, connect the Gateway to a non-production agent space, and classify each tool before you enable it. The following resources cover each step.

What Link
AWS DevOps Agent overview Product page · User Guide
Connecting MCP servers to AWS DevOps Agent User Guide – Connecting MCP Servers
AgentCore Gateway Developer Guide – Gateway · Getting started
Cedar policy for Gateway Understanding Cedar · Core concepts · Schema constraints
AgentCore runtime (MCP hosting) Deploy MCP servers in Runtime
Private connectivity VPC Lattice egress · Private endpoints · DevOps Agent private connections
Observability Service-provided observability · Observability overview
Gateway authentication Inbound auth setup · Cognito as IdP
Related blog posts Transform your MCP architecture with Gateway · Connect API Gateway to AgentCore Gateway · Why AgentCore chose Cedar
MCP/ACP samples DevOps Agent ACP/MCP samples
Samples DevOps Agent + CloudWatch sample


About the authors

Lakshmi Kumkala

Lakshmi Kumkala

Lakshmi is a Senior Technical Account Manager at AWS. Lakshmi works with enterprise customers on DevOps, operational excellence, and agentic AI architecture.

Hima Atluri

Hima Atluri

Hima is a Technical Account Manager at AWS, Global Financial Services. Hima helps customers build secure, observable operational workflows using AWS native services and agentic AI.

Building a gated review pipeline for AI coding agents on AWS

Post Syndicated from Owen Hawkins original https://aws.amazon.com/blogs/devops/building-a-gated-review-pipeline-for-ai-coding-agents-on-aws/

AI coding agents have changed the economics of writing software. Tools like Kiro turn specifications into working code, tests, and documentation, and a single agent can open dozens of pull requests across your repositories in an afternoon. What they have not changed is the number of senior engineers available to review those pull requests. The AI Productivity Paradox research from Faros AI drew on telemetry from more than 10,000 developers. It found that teams with high AI adoption merged 98% more pull requests while review time rose 91%. The gains did not show up in company-level delivery metrics. The constraint moved downstream, from writing code, to reviewing it.

The intuitive fix is to add an AI reviewer to every pull request. The evidence says that alone is not enough. Human-Centric to Agentic Code Review, a study of 1.02 million pull requests across 207 open source projects, found that reviews involving AI agents reached decisions faster but did not improve quality. After AI reviewers took part, the strongest factor explaining review efficiency was not the tooling, but how humans and agents were wired together in the review flow.

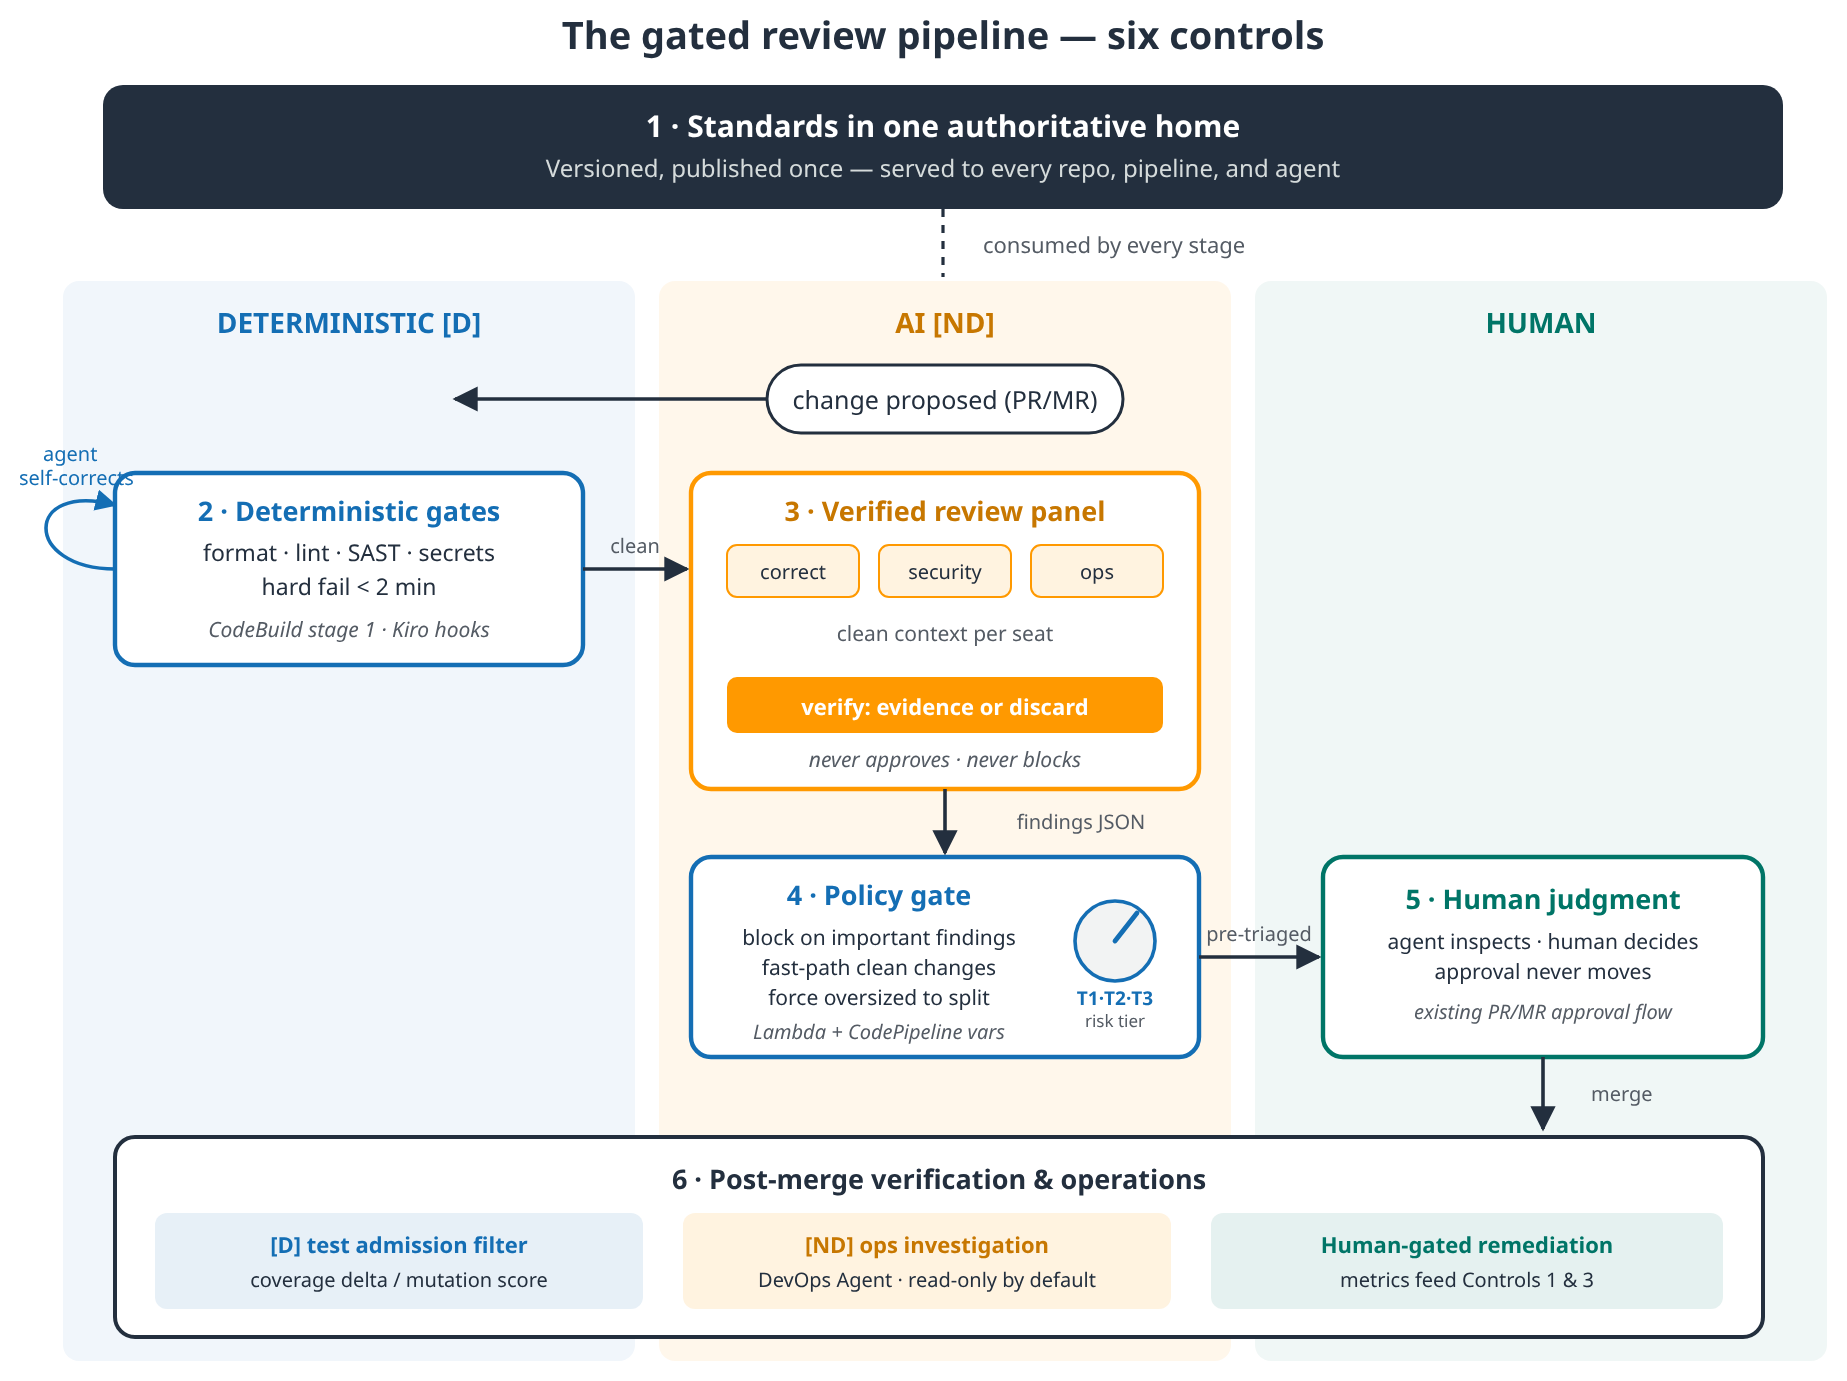
This post presents a pattern for wiring together humans and agents as part of code review. It introduces a gated review pipeline with six controls that pairs deterministic checks with verified AI review, applies your policy through risk-tiered gates, and keeps humans in charge of every consequential decision. It describes the core components of each control, how to implement them with AWS services, and how to measure the effect on defect and rework rates.

Two kinds of controls, and one wiring pattern

The AWS Blog Balancing speed and safety: a control framework for AI coding agents establishes a control taxonomy for what agents produce, through author-time controls (steering documents, specifications, and agent hooks) and pipeline scanning. It also introduces an AI-assisted review control. In this post, we expand that control into an operational design pattern. The pattern includes a review panel that produces verified findings, a deterministic gate that applies policy to findings, risk tiers that set agent autonomy, and metrics that show whether defect and rework rates fell.

This pipeline adds two design rules to that foundation. The first is a deliberate pattern for human and agent collaboration, because the research cited earlier found that collaboration patterns shape review efficiency. The second is risk-tiered autonomy. A documentation fix and a payments change carry different risk, so they shouldn’t pass through the same gate.

Assign the initial tier deterministically from what the change touches, not from what the author declares. Certain critical paths and files should be assigned the highest risk tier regardless of the change, for example changes to build and pipeline definitions, the Control 4 policy bundle, steering files, and the panel reviewer prompts. Changes such as a new dependency or an AWS Identity and Access Management (IAM) policy change should also escalate the risk tier. Evaluate related changesets together so a high-risk change can’t be split into low-risk pieces.

Tier Change risk Autonomy Review depth Evidence required
T1 Low (docs, internal tooling) Agent drafts, human approves Light spot-check Pull request + provenance tag (agent, model, requester)
T2 Medium (standard features) Agent drafts, engineer edits Full review + tech-lead sign-off Pull request + tests + approved spec or design notes
T3 High (payments, auth, data, changes to pipeline configuration) Agent assists, engineer implements Two human reviewers, plus architecture review when the design changes Full audit package
Diagram of the six-control gated review pipeline across deterministic, AI, and human columns, from standards through deterministic gates, the verified AI review panel, the policy gate, human judgment, and post-merge operations

Figure 1: An overview of the six controls in the gated review pipeline

The framework is methodology-agnostic. It composes naturally with structured approaches such as the AI-Driven Development Life Cycle (AI-DLC), but requires none of them. Where a team approves the specification before generation, that review settles whether this is the right change before any diff exists, leaving the pull request review to confirm it was built correctly.

Control 1: Standards consumable from one place

Code quality rules, architectural preferences, security standards, and compliance requirements each have an authoritative home where they’re owned, versioned, and published. Those homes can differ. A security team might keep a policy repository, compliance teams a wiki, and architects a decision log. All of these should feed a single consumption endpoint, so that every repository, pipeline, and agent pulls the same standards through the same mechanism instead of integrating with each source directly. Curating organizational knowledge into a form agents can consume is an easily underestimated investment. Funneling it through one consumption point means you make that investment once, not once for each repository and each source.

A single consumption point doesn’t require a single delivery mechanism. Retrieve situational standards on demand. Small, non-negotiable ones, such as production-safety guardrails, inclusive-language rules, and conventions for working with internal systems, belong in context on every interaction. Push those as baseline configuration, such as a global steering file or default agent configuration, so the agent doesn’t need to fetch them.

On AWS: Keep each standard in its authoritative home and put a single consumption layer in front of them. AgentCore Gateway, a capability of Amazon Bedrock AgentCore, can serve as that consumption point. It exposes each source as Model Context Protocol (MCP) tools from configuration alone, whether the source is a Git repository behind its provider’s MCP server, an HTTP endpoint, or Amazon Bedrock Knowledge Bases built over documents in Confluence or Amazon Simple Storage Service (Amazon S3). Every agent and tool then pulls the same versioned standards at runtime. The knowledge base is a retrieval layer for prose-style guidance that benefits from semantic search. It isn’t the system of record, and the owning team’s repository or document store remains authoritative. If you need evidence of which standard was in force for a given change, either sync a pinned copy into the repository as a pipeline step and record the version, or write the consumed standard version to an audit log at time of use. Deterministic consumers, such as linter configurations and the Control 4 policy bundle, should take the pinned path. A standards change then arrives as a version bump instead of failing every repository’s next build.

In the developer’s environment, the consumption format is whatever the agent reads, such as Kiro steering files or agent skills. Generate or sync those files from the gateway instead of writing them for each repository, so a local project becomes one more consumer of the same standards. For the always-on class of standards, generate the global steering files or default agent configuration from the gateway’s sources, and push them out through whatever provisions your developer environments. The gateway remains the on-demand path for situational standards.

Control 2: Deterministic gates first, with agent self-correction

The first gates to run are fast, deterministic, and hard-fail. These include formatting, lint, type checks, static application security testing (SAST), and secrets scanning. The remediation agent then self-corrects in a build, fail, fix loop until the stage passes or hits a maximum iteration cap, which hands the change to human review. Don’t use AI to review what a rule can catch. When the deterministic gates run first, the AI review stage sees only mechanically clean code and spends its reasoning on semantics instead of style. It also keeps most mechanical defects out of human review.

The self-correction loop is told to make the gates pass, and the shortest path to a passing gate is often a weaker gate. Treat suppression annotations, threshold changes, and removed or skipped tests in agent commits as change risk escalations.

The blog CI/CD Pipelines with agentic AI describes how Elastic does this. When a build fails, an agent steps in as a pipeline stage. It reads the failure logs, applies fixes from a deterministic tool allowlist, verifies the build, and commits, with auto-merge turned off whenever agent commits are present. In its first month, covering under half of Elastic’s dependencies, it fixed 24 broken pull requests and saved 20 days of development work.

On AWS: Run the same gates in two places. In the developer’s environment, Kiro agent hooks run them on file save and task completion. That catches defects before a pull request exists, where the fix loop is cheapest to run. The pipeline is the enforcement backstop. The same gates run in AWS CodeBuild on every pull request as a required status check, so a failing gate blocks the merge and nothing reaches review on the strength of a local run alone. Order them by cost and severity, as the predecessor post describes: secrets detection, SAST, software composition analysis (SCA), and then infrastructure as code (IaC) scanning.

When a pipeline gate fails, a remediation agent takes over. Because this agent commits to the repository, host it as a harness on AgentCore runtime, a capability of Amazon Bedrock AgentCore, outside the build, and call it from the failing CodeBuild action. The harness runs the agent loop in its own managed workspace. It treats the failure logs as untrusted data, applies fixes constrained by a tool allowlist, re-runs the gates, and commits to the source branch, reporting progress back to the pipeline. Authenticate that call with the pipeline’s IAM role so the automation runs on a workload identity you control, with no developer credential embedded in the build. Bound the loop with the harness’s execution limits. Cap fix attempts, set a wall-clock timeout, and give the agent a token budget. Count them per pull request, because each agent commit starts a new build. When any limit trips, the build stops and hands the failure to a human. Configure branch protection to dismiss approvals on new commits, so an agent fix always gets a fresh human review. For standing up the harness itself, see Hosting coding agents on Amazon Bedrock AgentCore.

Control 3: AI review as a verified panel

Run AI review as a panel of reviewers with distinct focus areas, for example, correctness, security, operational readiness, and, where the change was built from an approved specification, scope. Each seat on the panel is an agent that starts from its own clean context, which keeps it from inheriting assumptions about the code. Give each seat the diff as its focus, plus the full changed files and the dependencies they touch, so it reviews the change in context. An agent that sees only the changed lines can’t judge cross-file or architectural impact, and those are the defects most likely to survive the deterministic gates. From a security perspective, the code is untrusted input, so seats should be limited to sandbox environments with read-only tools.

Two sessions of the same model share the same blind spots. For each focus area on the panel, assign at least one agent to use a different model family than the author recorded in the provenance tag. For high-risk changes, you might run multiple agents with different models for the same focus area. Choose models by measurement. Evaluate candidates against past pull requests with known findings and prioritize models that score best for that focus area.

A two-stage verification step decides what reaches a human at the review gate. The first stage is deterministic. It confirms that the cited file and line exist and that the quoted code matches what’s there. A deterministic check can’t tell whether an anchored finding describes a real problem, which is a semantic judgment. The second stage can use a decision model, which returns one bounded answer (valid, invalid, or escalate to a human) with a confidence score. Because the answer is bounded, you can measure it. Evaluate the model against past findings with known outcomes, calibrate its thresholds, and route low-confidence cases to a human. Without this filter, volume works against you, as seen in one industrial deployment of a large language model (LLM)-based review tool. Average pull request closure time rose by more than 40%, even though developers acted on most of the automated comments.

On AWS: Run the panel seats as a single AWS CodeBuild batch build graph, one build per seat, each invoking an agentic coding harness in a fresh session and writing its findings to Amazon S3 under the commit’s key. Mount the checked-out repository so each seat has that context. The agents run inside CodeBuild because they only read code the build has already checked out, in an environment discarded after the run. The remediation agent in Control 2 writes to the repository, so it runs on AgentCore runtime under its own identity and limits.

A verification build that depends on the agents then reads their findings and runs the two-stage check. The deterministic pass checks each finding against the checked-out code and discards any finding whose file, line, or quoted code doesn’t match. A validity judgment then runs on what remains. The open source Strands Decider models fit that judgment, returning a bounded valid, invalid, or escalate classification with a confidence score. The verified, high-confidence set passes to the Control 4 gate, and low-confidence cases go to a human. For the security seat, you can use an open source harness such as the Visa Vulnerability Agentic Harness, which applies the same pattern to vulnerabilities. It uses deterministic stages for repeatable work and agentic stages for judgment, verifies each finding adversarially, and produces Static Analysis Results Interchange Format (SARIF) output that a gate can read. Run your chosen harness in a detection-only mode, so it emits findings without editing code, and feed its output to the same verification step and gate as the other agents.

Control 4: A deterministic policy gate on structured findings

The AI review panel in Control 3 never approves or blocks. It emits structured findings, each with a severity (important or minor), whether this change introduced it or it was pre-existing, and its evidence. Findings use a standard format such as SARIF, so deterministic and AI findings reach the gate in the same shape. A deterministic gate then applies your policy to that signal. It blocks on important findings, fast-paths clean changes, forces oversized changesets to split, and scales all of it by risk tier. Keeping policy in a deterministic component, apart from the model judgment it acts on, is the core of this pipeline. It makes the merge gate auditable, reproducible, and tunable for each repository. An empty finding set means the panel found nothing, not that nothing is there. Fast-path rules might shorten the queue for T1 changes but should never reduce human review depth at T2 or T3.

On AWS: Have the verification build write the verified findings to Amazon S3, keyed to the commit, as the record of that run. Then make the gate itself policy as code. A CodeBuild step or an AWS Lambda function evaluates the findings against rules written in Open Policy Agent or Cedar. The rules encode the preceding policy, scaled by risk tier. Oversized changes reach the gate less often when the specification breaks work into reviewable tasks. The gate reports to the pull request as a status check and posts a severity summary, for example “2 important, 4 minor,” before the verified findings. The rules ship in the pinned standards bundle from Control 1, so changing the merge bar means publishing a new policy version.

Control 5: Human judgment on a pre-triaged change

Human review remains a key pipeline component. What changes is what the human reads. Instead of a raw diff, the reviewer gets a change that the gates have made mechanically clean and the panel has triaged into ranked, evidence-backed findings. The reviewer no longer needs to catch what rules and agents already catch, and can focus on the judgments only a person can make. Is this change worth its risk? Does it fit the system’s design? Does it carry business context the agents never had? Are the important findings resolved, or only acknowledged?

Scale the depth to the tier: a T1 change needs one approver doing a light spot-check, a T2 change a full review with tech-lead sign-off, a T3 change two human reviewers plus architecture review when it changes a design boundary. The person who directed the agent is the change’s author and doesn’t count toward its reviewers. Review depth scales with risk, and the human decision is never delegated.

On AWS: Your existing pull request approval flow stays the baseline human gate. The panel’s verified findings land as review comments with a severity summary at the top, so the approver starts from a pre-triaged change. For T3 changes, require a second human reviewer before merge, and use your source provider’s approval rules to block approval by the requester. After merge, an AWS CodePipeline manual approval action adds a second recorded decision before production. It notifies approvers through an Amazon Simple Notification Service (Amazon SNS) topic routed to wherever they already work. Have the tooling that runs the agent, not the agent itself, write the provenance tag as commit trailers that record the agent, model, session, specification, standards version, and requester.

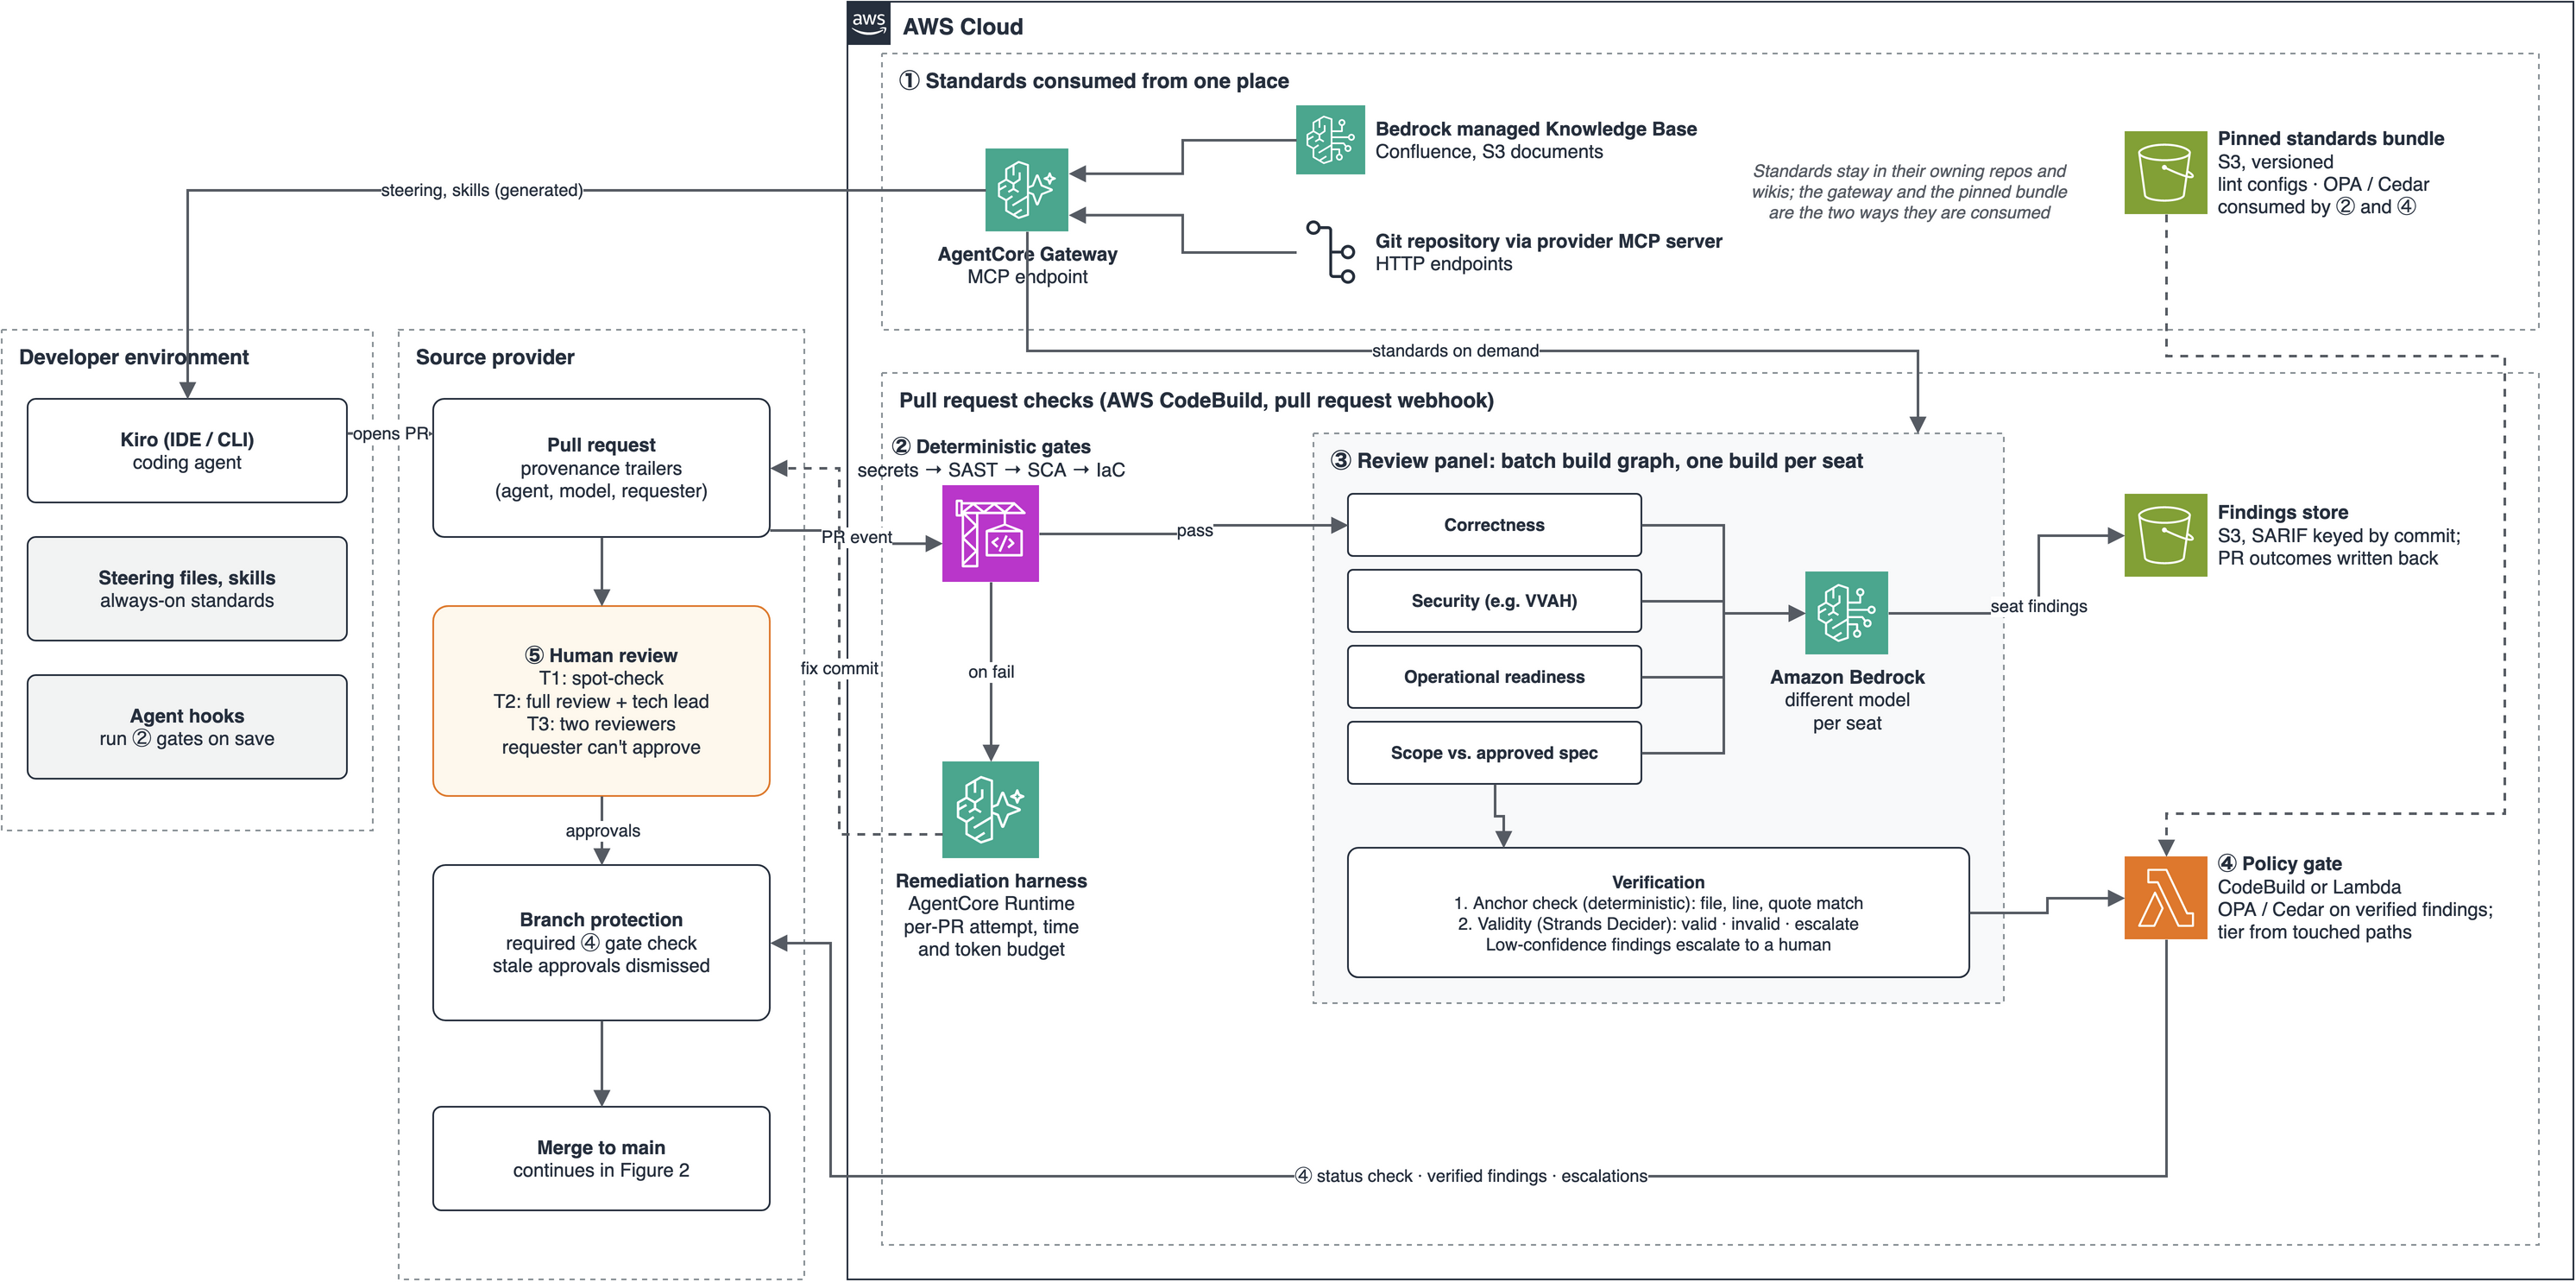
Architecture diagram of the pre-merge flow in AWS Cloud, where AgentCore Gateway serves standards to the developer environment and pipeline, deterministic gates run in CodeBuild, a four-seat AI review panel writes verified findings to an Amazon S3 store, and a Lambda policy gate and branch protection enforce tiered human review before merge

Figure 2: The pre-merge pipeline, where standards, deterministic gates, the verified review panel, and the policy gate run as pull request checks and branch protection enforces the gate and the tiered human review

Control 6: Post-merge verification and operations

The same logic extends after merge. Tests that ship with a change go through Controls 2 and 3 with the change. This control covers suite-improvement tests that an agent generates against existing code. Meta’s TestGen-LLM is an example. It admits a generated test only after the test clears filters showing that it measurably improves the existing suite. Admit these tests as you would untrusted contributions. They must build, pass reliably across repeated runs, and measurably improve the suite, through a coverage delta or a mutation score, before a human spends time on them. The filter removes tests that add nothing, but it can’t tell whether the asserted behavior is correct, because a test generated against existing code records what the code does today. That judgment belongs to a person, and it matters more here. A test that pins wrong behavior into the regression pack blocks the future change that fixes it. Tests that clear the bar join the regression pack that the deterministic gates run on every later change, so post-merge generation keeps strengthening the pre-merge gates. In operations, agents investigate on their own, reading telemetry, correlating signals, and proposing mitigation plans, while a person approves any remediation.

On AWS: Enforce the coverage or mutation threshold in a CodeBuild project that runs as an action in a dedicated stage of your CodePipeline. A generated test that doesn’t measurably improve the suite fails the build and never reaches the regression pack. This is the same mechanism as Control 2, pointed at a different signal. There, the build fails on lint, type, or SAST violations. Here, it fails on a coverage delta or mutation score that doesn’t clear the bar. For operations, AWS DevOps Agent fits this split. It’s read-only by default, investigating pipeline and operational failures and proposing mitigation plans for a person to approve.

Measuring whether it works

The research cited earlier found that AI review made decisions faster without making them better. Cycle time is the number most readily moved, and it can improve while quality degrades. Track review cycle time, because review is the constraint this approach exists to relieve, but only alongside the following quality measures. Avoid lines of code and pull request counts entirely, because they measure activity, not outcomes.

Measure instead:

  • Defect escape rate and rework rate – Bugs found after merge, and changes that need follow-up fixes.
  • Change failure rate and time to restore – The DevOps Research and Assessment (DORA) stability metrics, which show whether stability held as change volume grew.
  • Finding acceptance rate per panel seat – A falling rate means the seat is getting noisier, or that reviewers have stopped engaging with its findings. Check the seat first.
  • Panel recall – The share of escaped defects the panel would have flagged, found by replaying them through it. Acceptance shows what the panel gets right, and recall shows what it misses.
  • Changeset size drift – Agents will absorb ever-larger diffs if you let them. Keep changes small even as more of them are automated.
  • Cost per accepted finding – Model and compute spend divided by the findings that reviewers acted on, by seat and tier. It shows which seats earn their place and where tier policy should run fewer.

For the executive rollup, cost to serve software, defined as total delivery cost divided by units of value delivered, captures the whole system. Faster generation that creates more review burden shows up as a worse cost to serve. Pair cost to serve with tension metrics, such as security incidents and rollback rate, so the number can’t be improved by cutting controls. Developer experience work at Amazon reported a 15.9% year-over-year reduction on this measure in 2024.

On AWS: Measure from the signals the pipeline already emits instead of building a parallel system. Route CodePipeline and AWS CodeDeploy deployment events, plus your incident records, through Amazon EventBridge to AWS Lambda and into Amazon CloudWatch for the change failure rate and time-to-restore metrics. The DORA metrics sample is a useful reference for wiring this up. The review-quality metrics come from artifacts the pipeline already writes. Query the Control 4 findings store in Amazon S3 with Amazon Athena for acceptance rate per seat and changeset size drift. For that, the gate records each change’s tier and size in its report, and each finding’s outcome on the pull request (resolved or dismissed) is written back to the store. Defect escape and rework rates need one deliberate link. Tag post-merge defects and their follow-up fixes back to the commit that caused them, so the numbers attribute to a change.

Roll the executive view up in Amazon QuickSight, showing cost to serve software alongside the tension metrics that keep it from being gamed.

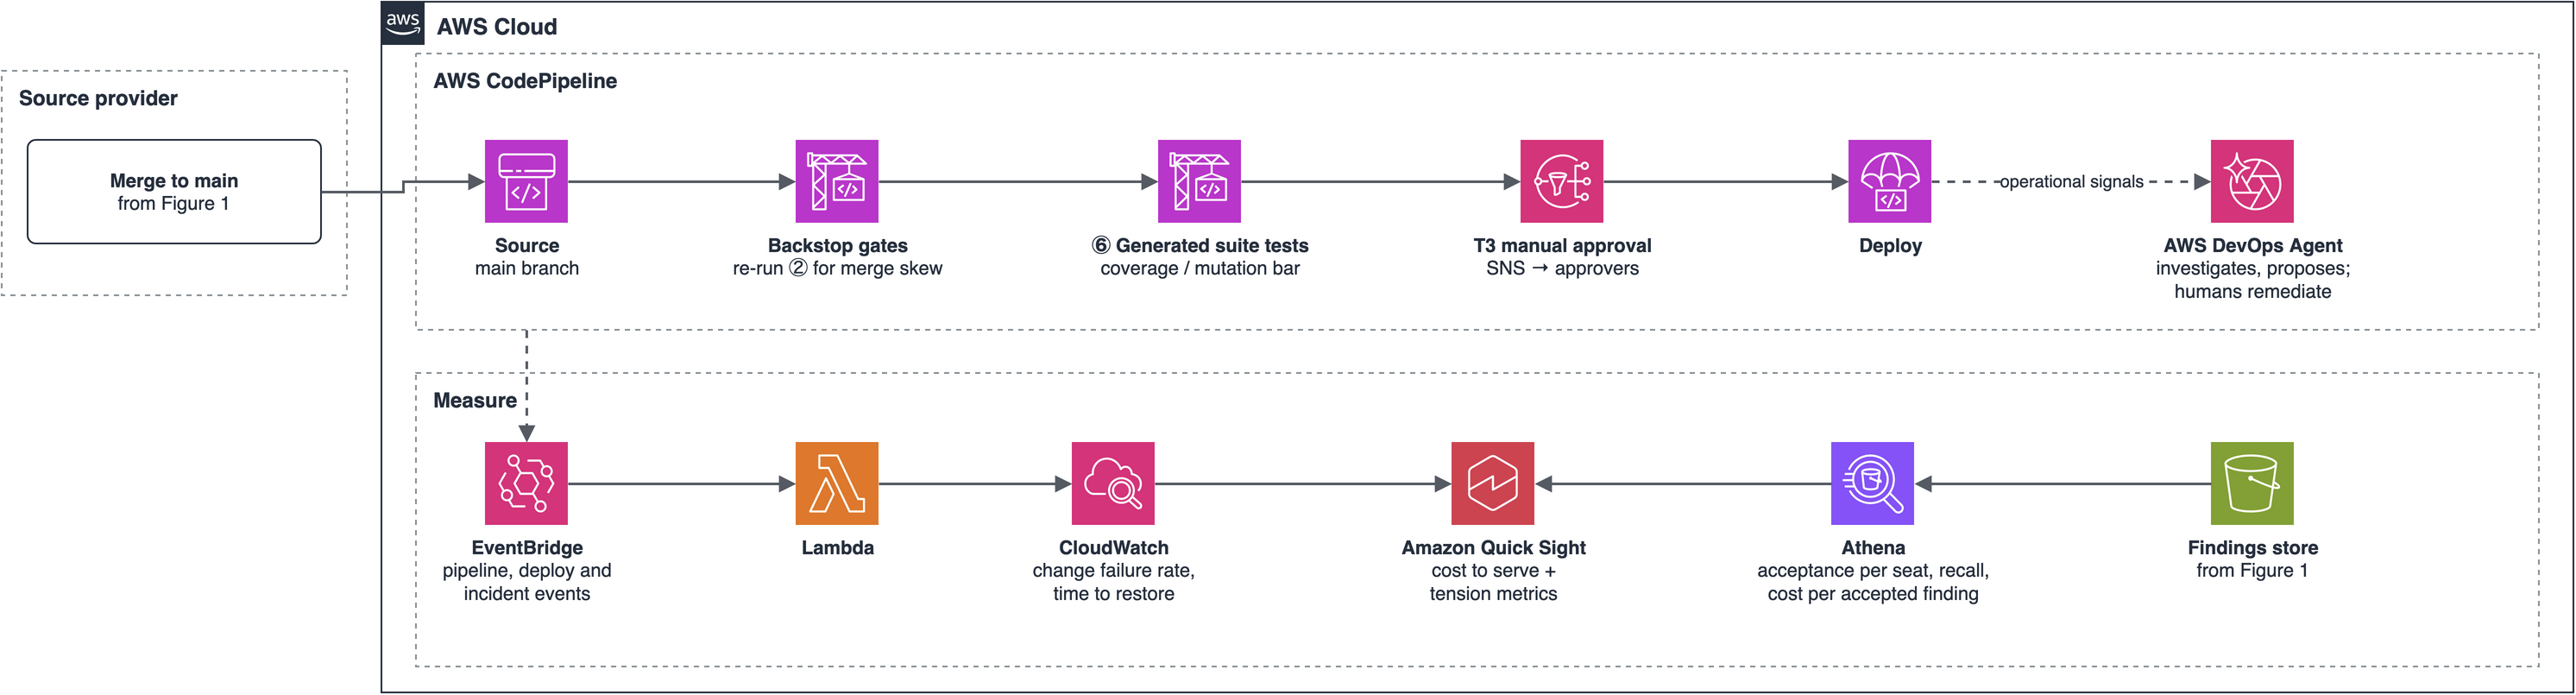
Architecture diagram of the post-merge flow, where an AWS CodePipeline re-runs backstop gates, admits generated suite tests, requires T3 manual approval before deploy, and uses AWS DevOps Agent for operations, while Amazon EventBridge, AWS Lambda, Amazon CloudWatch, Amazon Athena, and Amazon QuickSight produce delivery and review-quality metrics

Figure 3: The post-merge pipeline re-runs the gates, admits generated tests, adds the T3 approval before production, and feeds delivery and review-quality metrics

An incremental adoption path

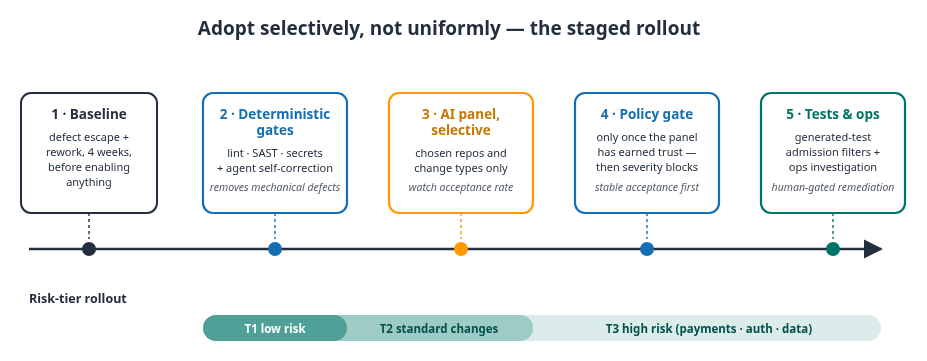
Roll the pipeline out in stages instead of all at once. Each stage produces the evidence you need to trust the next. A baseline tells you whether anything improved, airtight deterministic gates show what the panel adds beyond rules, and an advisory panel shows whether its findings deserve to block.

  1. Baseline first. Capture defect escape and rework for four weeks before you turn anything on, or you will have no evidence story. Expect escape rates to lag, because defects surface weeks after merge. Rework moves sooner.
  2. Deterministic gates next. Get Control 2 airtight with the agent self-correction loop. This step alone keeps most mechanical defects out of human review.
  3. Add the panel selectively. Pick starter repositories with high pull request volume and moderate (T2) risk, where you get signal fast without affecting a critical system. In this phase, the panel is advisory. It posts findings but doesn’t block anything, because the policy gate isn’t wired yet. Use this window to confirm its value. Watch the finding acceptance rate, and check whether the panel surfaces real issues your reviewers were missing before you let severity block anything.
  4. Wire the policy gate only after the panel has earned trust. When acceptance rates are stable and engineers act on the findings, let severity block merges.
  5. Extend to tests and operations last.The same evidence can widen agent autonomy over time, for example letting the remediation agent fix verified findings in categories where the panel has proven reliable. Teams with long-established trust in their pipeline sometimes go further and auto-merge low-risk changes, as the Kiro Crew team describes.
Timeline of the staged rollout: a measurement baseline, deterministic gates, a selective AI panel, the policy gate, and then tests and operations, aligned to rising risk tiers from T1 to T3

Figure 4: The staged rollout, from a measurement baseline through deterministic gates, a selective AI panel, the policy gate, and finally tests and operations, aligned to rising risk tiers

The same pipeline, two changes

The following table follows a T1 change and a T3 change through all six controls. The pipeline is the same for both. What changes is autonomy and review depth.

Control T1: fix a broken link in the README T3: change refund-retry logic in the payments service
1. Standards Pulls the same standards, and the always-on security and compliance guardrails that are baseline config for every change
2. Deterministic gates Formatting and link-check run, pass, nothing to self-correct SAST, secrets, SCA, and IaC scans run. The agent self-corrects a flagged dependency, re-runs, and passes within the bounded loop
3. AI review panel Skipped by T1 policy, because the Control 2 link check already verified the fix Full panel runs with repository context. The security and correctness seats flag an auth-scope concern on the retry path, which is verified and passed to the gate
4. Policy gate T1 policy: no important findings, fast-path to a single approver T3 policy: an important finding blocks, oversized-diff check passes, routed for full review
5. Human review One approver, light spot-check, merge Two human reviewers, and the auth-scope finding must be resolved, not only acknowledged. T3 adds the CodePipeline manual approval before production
6. Post-merge Nothing further Agent-generated suite-improvement tests on the touched module must clear the coverage bar before a human looks. Operational signals are watched after deploy

Conclusion

AI coding agents are accelerating code generation and making code review the constraint. Adding an AI reviewer doesn’t remove that constraint on its own. Outcomes depend on how humans and agents are wired together. In this post, we showed a pipeline that wires them together to speed up review while reducing risk. Deterministic rules catch the first issues. A verified panel reviews what remains and emits a structured signal, a deterministic gate applies your risk-tiered policy to that signal, and a human makes the final call on a pre-triaged change. The same pattern extends to generated tests and operations.

Before you implement this pattern, read the predecessor post, Balancing speed and safety: a control framework for AI coding agents, which covers the author-time controls this pipeline assumes. To implement Controls 1 and 2, explore Kiro steering files and agent hooks. For broader control guidance, see the AWS Well-Architected Agentic AI Lens. If you try this pattern, tell us what you learn in the comments.

If you’re attending AWS re:Invent 2026, join us in the workshop SEC416, where participants get hands-on experience building out this pattern.


About the authors

Owen Hawkins

Owen Hawkins

Owen is a Principal Solutions Architect at Amazon Web Services, working with independent software vendors in the UK. Building on more than 20 years in information security and digital banking, he now spends his time on agent identity and on helping engineering organizations improve their software development lifecycle with AI-driven approaches.

Trevor Schiavone

Trevor Schiavone

Trevor is a Senior Solutions Architect at Amazon Web Services where he partners with enterprise customers to design and implement cloud and AI solutions. With over 10 years of experience spanning software engineering, cloud architecture, and artificial intelligence, he brings a practical, customer-driven perspective on how organizations can innovate responsibly with AI.

Chris Williams

Chris Williams

Chris is a Senior Solutions Architect at AWS, based in London, where he supports independent software vendors (ISVs). A software engineer by background, he has been building on AWS for over a decade, with over five of those years at AWS. He specializes in the software development lifecycle (SDLC), helping engineering teams improve how they plan, build, test and ship software. His work covers everything from CI/CD and infrastructure as code to AI coding assistants such as Kiro and the AI-Driven Development Life Cycle (AI-DLC). DevOps has always been his passion.

Using the AWS RMiT workbook and ISO Compliance Guides to support your BNM submissions

Post Syndicated from Jonathan Jenkyn original https://aws.amazon.com/blogs/security/using-the-aws-rmit-workbook-and-iso-compliance-guides-to-support-your-bnm-submissions/

Your next Bank Negara Malaysia (BNM) notification submission needs auditable evidence of how Amazon Web Services (AWS) controls align with Risk Management in Technology (RMiT) requirements. Two resources now exist to support that work: the AWS Workbook for BNM RMiT and the compliance guides published by AWS Security Assurance Services (AWS SAS).

The AWS Workbook for BNM RMiT, available through AWS Artifact, maps each RMiT provision to AWS Control Objectives (AWS responsibilities under the AWS Shared Responsibility Model) and AWS Well-Architected Framework best practices (your responsibilities). It tells you, for every RMiT requirement, what AWS is responsible for and what you implement.

The compliance guides published by AWS SAS over the past year provide implementation guidance for International Organization for Standardization (ISO) and International Electrotechnical Commission (IEC) standards that complements the workbook. These guides show how to implement controls that meet the requirements of specific standards and frameworks using AWS services, giving your technical and compliance teams a clear path from regulatory expectation to deployed architecture.

Malaysian financial institutions can now trace from BNM regulatory requirement, through AWS control implementation, to the evidence that demonstrates it: AWS third-party attestations for AWS-side controls, and your own workload evidence for customer-side controls. BNM expects this specificity in notification documentation.

AWS Workbook for BNM RMiT

The workbook is a structured Excel document available through AWS Artifact. For each of the 394 RMiT provisions, it identifies:

  • Whether the requirement is an AWS responsibility or a customer responsibility under the Shared Responsibility Model
  • The specific AWS Control Objective that addresses the requirement (where AWS is responsible)
  • The relevant AWS Well-Architected Framework best practice for customer implementation (where the customer is responsible)
  • Supporting information and references for each mapping

The following is a sample entry from the workbook:

RMiT Requirement Responsibility Source AWS supporting information
10.49: A financial institution should ensure network resilience… AWS AWS Control Objectives AWS Control Section: Network Security. AWS maintains redundant network connectivity with multiple tier-1 transit providers across each Availability Zone.
10.49: (Customer responsibility) Customer Well-Architected REL 2: How do you plan your network topology? Implement multi-AZ deployments. Configure VPC flow logs and use AWS Network Firewall.

The workbook currently includes 394 rows across all RMiT appendix requirements, with 208 mapped to AWS responsibilities and 186 to customer responsibilities.

Why this matters now

BNM revised RMiT guidelines effective 28 November 2025, and updated them on 25 September 2026 to add requirements for National Critical Information Infrastructure (NCII) entities. Financial institutions operating under both BNM Outsourcing and BNM RMiT must demonstrate that their cloud service providers maintain controls aligned with regulatory expectations. Institutions preparing notification submissions for material cloud workloads need auditable evidence of this alignment.

The revised guidelines set higher expectations for evidence quality. Institutions submitting notifications without clear, structured control mapping evidence might face extended review cycles and requests for additional information from BNM. Workloads that could be deployed in weeks remain in governance queues for months when supporting documentation lacks the specificity regulators expect.

Compliance guides from AWS Security Assurance Services

Start with the RMiT workbook to identify which provisions AWS addresses and which you implement. Then use the following compliance guides to design and implement your customer-side controls. The guides are implementation guidance for your teams. Audit evidence comes from two places. For AWS-side controls, use AWS third-party attestations, such as ISO certificates and System and Organization Controls (SOC) reports, available in AWS Artifact. For your workload, use evidence from your own environment, including configurations, logs, and AWS Config conformance pack results. Auditors can also use the guides as a reference for how a control is typically implemented on AWS.

AWS SAS has published five compliance guides over the past year. Each guide provides control-level implementation guidance on the customer side of the Shared Responsibility Model, showing how AWS services can be configured to meet the requirements of specific standards and frameworks. These guides were written by AWS SAS practicing security assessors and auditors holding Payment Card Industry Qualified Security Assessor (PCI QSA), Certified Information Systems Security Professional (CISSP), Certified Information Security Manager (CISM), ISO 27001 Lead Auditor, and Certified Cloud Security Professional (CCSP) certifications, drawing on experience from hundreds of cloud security assessments across financial services globally.

The following is the list of guides AWS SAS practicing auditors have published, which include control mapping information relevant to BNM RMiT:

How these resources work together

A Malaysian financial institution preparing a BNM notification can use these resources together:

  • The RMiT workbook identifies which RMiT provisions are AWS responsibilities and which are customer responsibilities.
  • For AWS responsibilities, the workbook references the specific AWS Control Objective.
  • AWS third-party reports in AWS Artifact, such as the AWS ISO/IEC 27001 certificate and SOC reports, attest to those AWS Control Objectives. For customer responsibilities, the ISO compliance guides show how to implement the corresponding controls using AWS services.
  • The ISO 31000 guide can inform the risk management methodology you apply to your cloud workloads.
  • AWS Config Conformance Packs for BNM RMiT provide automated, continuous monitoring of deployed controls.

Resources also supporting this approach:

Compliance teams across Association of Southeast Asian Nations (ASEAN) financial services have already begun referencing the AWS Guide to BNM RMiT and associated resources in their cloud risk assessment processes and BNM notification documentation.

Looking ahead: AI governance

For institutions deploying generative AI and machine learning, ISO/IEC 42001:2023 (Artificial Intelligence Management Systems) is relevant to BNM technology governance expectations. In November 2024, AWS became the first major cloud provider to announce ISO/IEC 42001 certification for AI services. AWS passed its first surveillance audit in November 2025 with zero findings. The ISO 42001 compliance guide published in May 2026 supports institutions building their own responsible AI systems on their side of the AWS Shared Responsibility Model.

How to get started

  • Access the RMiT workbook through AWS Artifact and review with your compliance lead to identify which provisions apply to your material cloud workloads.
  • Download the relevant ISO compliance guides to plan how you implement your customer-side controls. Download AWS ISO certificates and SOC reports from AWS Artifact for AWS-side evidence.
  • Map your workload-specific controls using the workbook as the RMiT baseline and the ISO guides as implementation guidance.
  • Implement automated compliance monitoring using the BNM RMiT conformance pack for AWS Config to maintain continuous visibility over your control posture.
  • Engage your AWS account team or AWS SAS for additional guidance on implementing customer-side controls referenced in the workbook.

As BNM updates its regulatory expectations, AWS will update these resources to reflect revised requirements. Subscribe to the AWS Security Blog for update notifications.

Additional resources

If you have questions about this post, contact AWS Support or start a new thread on AWS re:Post.


Jonathan-Jenkyn

Jonathan Jenkyn

Jonathan (JJ) is a Senior Security and Compliance Solutions Architect with AWS Security Assurance Services and a published cybersecurity author. He has over 30 years of experience across penetration testing, incident response, cyber resilience, and security governance. He helps customers build practical security programs. He champions disability inclusion and neurodiversity at Amazon. Outside work, he runs, cycles, swims, and enjoys family time.

Matthew Nixon

Matthew Nixon

Matt is a Principal in the AWS Asia Financial Services Security and Compliance team. He has 20 years of experience in technology risk, audit, and information security, including leading a cloud risk team in financial services. Matt co-founded an award-winning AI/ML startup, authored books on IT and cloud risk, and won the Singapore ISACA 2024 IT Risk Leader Award.

Four Continents, Four New AWS Heroes: Closing Out 2026

Post Syndicated from Taylor Jacobsen original https://aws.amazon.com/blogs/aws/four-continents-four-new-aws-heroes-closing-out-2026/

As AWS re:Invent is around the corner, we’re proud to recognize a new group of AWS Heroes. Every Hero finds their own way to give back, whether through sharing what they know, bringing people together, or building tools that help others succeed. What they have in common is a genuine commitment to supporting the builders around them learn, grow, and lead.

Let us take a moment to meet them!

Andres Moreno – El Paso, United States

Serverless Hero Andres Moreno leads the Cloud del Norte AWS User Group and is a former AWS Community Builder. On his blog, And More Dev, and at conferences and community events, he explains serverless, cloud native architectures, generative AI, and agentic systems in ways that make new technology easier to try. Andres puts special energy into supporting builders across Latin America and helping them explore what’s possible on AWS.

Geethika Guruge – Auckland, New Zealand

Community Hero Geethika Guruge is a Principal Consultant at Mantel Group whose work spans serverless, DevOps, cloud infrastructure, and agentic AI. Geethika has shared real lessons from building agentic applications and leading large migration and modernization programs at AWS re:Invent, AWS Summits, and AWS Community Days. At home in Auckland, Geethika organizes local AWS meetups that encourage grassroots innovation and mentors the next generation of cloud architects and leaders.

Jéssica Cristina Coelho – Belo Horizonte, Brazil

Data Hero Jéssica Cristina Coelho is a Database Reliability Engineer and a former AWS Community Builder with more than 15 years of experience in databases, cloud, and data engineering. She leads the AWS User Group in Minas Gerais, hosts DataTalks Brasil, teaches MBA courses, and supports Women in Cloud, DevOpsDays, and AWS Community Day events. She speaks at events such as AWS Summit São Paulo and Web Summit Rio on database modernization and generative AI. At AWS re:Invent 2025, she was recognized as a LATAM Diversity & Inclusion Champion.

Kazuho Cryer Shinozuka – Tokyo, Japan

DevTools Hero Kazuho Cryer Shinozuka is an AWS CDK Top Contributor and Trusted CDK Community Reviewer. With 200 merged pull requests, he ranks 18th among more than 1,700 contributors. He has reviewed more than 120 pull requests, has been involved in about 2% of all CDK commits, and has published 10 construct libraries, along with tools such as cfn idle cost. Through talks at JAWS DAYS and CDK Conference Japan and through hands on contribution workshops, he helps more developers in Japan start contributing to open source.

Learn More

To connect with these Heroes or find one in your region, explore the AWS Heroes webpage, and join the conversation on AWS Builder Center.

— Taylor

Engineering AI Discover

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/engineering-ai-discover-e244944cdc38

The challenges and decisions behind AI Discover’s intelligence layer

By Varun Khaitan, Peng Ren, Gary Tang, Itay Teller, Atif Faheem, Nipun Kumar, Donnie DeBoer, Eduardo Lundgren, Matteo Rinaldi, Raghav Bakshi

We recently introduced AI Discover, a new tab in our TV app where a small group of members can try new ways to find something to watch. For years, our recommendations have worked in the background, inferring what a member might enjoy from their viewing history. AI Discover moves from that silent ranking toward steerable discovery. A member picks a theme, say “Quick Watches,” and gets a row of matching titles, a short note on why they fit and a few narrower themes to try next. From there, they can keep narrowing, head somewhere new or tune what they see.

Building AI Discover raised a question many teams will recognize: how do you deliver a better member experience with generative AI on TV without sacrificing speed, reliability or safety? Our answer is a new intelligence layer, the agent harness behind AI Discover. For each request, it decides how to combine LLMs with our recommendation systems. It builds on years of work understanding what members enjoy, and on our recent work applying LLMs to recommendations and generative experiences. The layer itself plans each request, runs it across those systems, serves the result and evaluates it offline.

This post covers the challenges we designed for and the key decisions we made along the way.

A visual walkthrough of the AI Discover experience launched on Netflix TV devices.

Why an intelligence layer?

Every Netflix page combines recommendations with rules. We pick titles a member may enjoy, and eligibility, maturity and safety rules decide what can appear. An experience built on LLMs needs the same rules, plus code that decides when to call an LLM and how to handle its output. That code is called an agent harness, and it’s the core of our intelligence layer.

The simplest implementation hands the entire request to an LLM and lets it pick the titles, write the labels and decide what happens next. However, that leaves us relying on probabilistic output where we need governed results, because every turn in AI Discover ends on a screen in someone’s living room. At our scale, even rare failures happen many times a day. A member sees every slow call, unavailable title or off-brand line. Seven challenges shaped our design:

  1. Fitting LLMs into a product and architecture designed without them. Traditional recommenders rank titles based on past behavior. LLMs can do more: understand what a member is asking for and plan how to respond. Our existing experience would leave most of that unused.
  2. Keeping recommendations grounded. Every pick must be a real, available title from our changing catalog. Retrieval and rankers work in tandem with LLMs to choose titles that fit the member’s taste and intent.
  3. Working with slow, unpredictable LLMs. LLM calls are the slowest and most expensive part of the system. Tail latencies can spike, and the output may not be what you asked for. So we use LLMs selectively, treat what they return as untrusted input and test performance and quality before anything ships.
  4. Adapting to fast-changing models, tools and prompts. Modeling and engineering solutions keep evolving, so the product can’t depend on any single model, tool or prompt.
  5. Building for TV. Typing on a TV is hard, so members rely on the remote, and the app should respond to every press right away on widely varying hardware. TV apps also update slowly, so changes have to ship without an app release. A typical TV request returns in moments, while multi-step generation can take several seconds.
  6. Holding a safety and reliability bar at scale. Members always get a page, even when an LLM call fails or yields poor results. Their choices and our content standards hold on every request, and when something breaks, structured records show why.
  7. Learning from what members say alongside what we already know. Recommendations have always learned from viewing behavior. AI Discover also lets members tell us what they want, and that has to shape what they see next.

System Architecture

When a member picks a theme, the TV app sends the request to the Page Server, which builds pages for all Netflix apps and hands the request asynchronously to the intelligence layer. At a high level, this new layer has two components: a controller and an executor.

The controller decides what to run. It gathers the context needed for each request, including real-time signals such as the time of day. It then settles on a plan, either an established one or a new one drafted by its planner, validates it and retrieves only the member details that this plan requires from Memory Hub, our per-member memory store. These details may include member taste summaries generated by MemberLLM, our in-house language model for personalized recommendations, or feedback shared by the member. We talk more about Memory Hub and member taste summaries later.

A plan is a graph of approved steps, each running a capability. A capability is a named unit of work that can have multiple versions and belongs to a family such as retrieval, ranking, generation or packaging. It declares its inputs and outputs, the context it may see and what happens if it fails.

Capability declarations make a plan verifiable. Before execution, the controller validates the graph: every step is approved, every input has a producer, nothing loops and the plan ends in exactly one page. Afterward, the controller checks the result before it’s served.

The executor runs the plan. Steps pass typed outputs to each other through the declared contracts, so each receives exactly what it asked for. Independent steps run in parallel, each with its own deadline and appropriate fallback behaviors. Some steps are optimized LLM calls with one task each, such as writing row titles or suggesting next themes, and they act only within the validated plan. Checks before the run and contracts during it give us governed execution, where every action stays within limits set in code.

Both parts write to the request records, the traces we use offline to evaluate and improve the system.

System Architecture Diagram

Key Decisions

Each challenge led to one decision. Here’s what we chose and what it bought us.

1. Design the product and architecture around LLMs

We reimagined the experience around LLMs. The easier path would have been to drop them in as rankers, keep today’s latency budgets and precompute where necessary. AI Discover is built on a back-and-forth around themes a member can steer, which gives LLMs work only they can do: generating themes, explaining rows, summarizing taste and helping choose the titles that fit the member and the moment. Members pick themes with the remote, so they never have to type. On the TV, those themes and explanations get their own native UI elements. Behind the screen, LLMs can draft plans, and asynchronous serving gives multi-step agentic orchestration the time it needs.

This opens up experiences our traditional stack couldn’t support on its own.

2. Make existing systems composable

Keeping recommendations grounded meant building on the systems that already know our catalog and members. Most capabilities wrap complex, proven Netflix systems such as search, large-scale ranking and catalog metadata access. Some of them may run their own agents in the future.

Reshaping them took careful work, because agentic orchestration challenges many long-standing assumptions of distributed systems. A capability now has to work in combinations no one designed, for a caller that chooses to call it at runtime. Each one needs a clear purpose and a semantic interface, and shaping it means deciding how much to combine into a single step and how much to leave to the planner. Too fine, and the planner has more ways to go wrong; too coarse, and it loses room to compose richer plans.

In return, the planner gets building blocks it can mix in new ways, and connecting services takes far less manual wiring. Because plans can only use these blocks, even one drafted on the fly stays grounded in our catalog and member taste.

3. Plan first, then execute

To contain LLM latency and errors, we plan every request before anything runs. The familiar way to let an agent use tools is a loop: reason, call a tool, read the result, reason again. It’s flexible, but you can’t tell up front how many steps it will take or whether it has gone down a wrong path. In agent terms, ours is a plan-and-execute agent: an LLM can propose the path, but code decides whether it runs.

Plans come from two places: established plans we’ve already tested, and plans an LLM drafts on the fly. A router we control decides which one is served. Either way, the plan passes the same checks before it runs. If the planner is slow or its plan fails a check, we fall back to a tested plan.

This allows for adaptive planning. The planner can find new ways to serve a request, and we can balance cost, latency and quality for each task, from a lean single-call plan to a richer multi-step one.

4. Stay model and capability agnostic

The best model or capability for a task today may be second-best, or overkill, in a few months, so we built the system to switch between them. We assign each task to the model or capability version that fits it. Today that’s a per-task setting we can override live. Only some steps in a request use an LLM.

That only works if switching is easy. All the LLMs we use sit behind one common interface. Before we switch, each candidate is scored on the same tasks by automated checks and LLM judges, so every swap is a measured change.

Much of the system’s behavior lives in server-side prompts and configuration, so we can swap models, tools and capabilities without new code or a TV app release.

Upgrades get cheap and experiments get easy. Moving to a better model, ranker or retrieval system is a plan or setting change, not a migration, so each component can keep improving without a large investment.

5. Make page generation asynchronous

Inference keeps getting faster, but member expectations rise just as quickly: richer responses, more context and more of the page shaped by LLMs. The line between what feels instant and what’s worth waiting for will keep shifting, so we built the asynchronous path as a first-class way of serving.

Most of a TV app is synchronous: press a button, get a page. Generative work breaks that pattern. Holding one request open for many seconds across services would tie up too many threads. So requests that involve generation are asynchronous. The press returns right away with an acknowledgement, and the TV switches to a thinking state that explains what’s being prepared. Meanwhile, the executor runs the plan in the background. When the result is ready, the server notifies the TV, which then fetches it.

Slow generation no longer slows anything else. The serving path stays healthy however long a turn takes, and every press still gets immediate feedback on screen.

Async Sequence Diagram

6. Enforce safety in code

Some rules must hold no matter what an LLM writes: content and maturity standards, what each step can access, and what a member has asked us not to show them. Putting those rules in a prompt makes them probabilistic, so we enforce them in code. Generated text is cleaned up before it reaches the screen. The planner sees a stripped-down request, and member details are limited to what the validated plan needs.

For example, the planner decides which inputs each step needs, such as the profile’s maturity rating for retrieval. Instead of writing parameter values directly, it uses placeholders. After the plan passes validation, the controller fills them with values from the request, matched by declared type. This also protects against prompt injection.

Each request also leaves a structured record: the plan, each step and its outcome, and which rules applied. When a page misses, we can tell whether the plan, the data, a rule or the model was at fault. The same records feed our offline evaluation and replay.

Together, these rules and records let an experiment ship at the same safety and privacy bar as the rest of the product.

7. Remember what members tell us

A taste summary is a short profile of what a member enjoys, such as favorite genres, tone and recurring themes. MemberLLM generates it ahead of time from the member’s viewing history, which keeps that LLM work off the request path. It helps us further personalize their page, and steps that write themes and explanations receive it as context, so their wording reflects the member. We’ll cover MemberLLM in more detail in an upcoming post.

In AI Discover, members can also tune their recommendations and tell us directly what they want. Those choices apply right away and carry across visits, and they give us a new signal alongside what we already know about their taste. This is a first step toward remembering more about each member, from their preferences to the habits that show up over time and the corners of the catalog they like to explore. We keep it all in Memory Hub, our persistent, low-latency memory store, next to their taste summaries, and we can add new kinds of memory as we need them. We apply these memories to later requests where they’re relevant, together with real-time context.

The member holds the remote

In this version, members interact by selecting themes and using tuning options such as “don’t recommend.” There’s no free-text input or open-ended chat. That keeps the LLM’s job narrow by design.

  • The usual protections still apply. Profile settings and our safety and privacy policies hold here as everywhere else.
  • Generated text was tested before launch. We ran safety evaluations on theme labels, row titles and explanations to make sure they meet our standards.

What’s next

It would have been faster to let an LLM do everything and stop there. The intelligence layer gave us an AI-native product, grounded building blocks, adaptive planning, quicker experimentation, asynchronous generation, governed execution and agent memory for tunable personalization. While AI Discover is its first experience, we designed it with more in mind.

We’ve organized our efforts to answer two questions:

  • How much do members want to shape their recommendations? Whether they’d rather steer or lean back, and how much, which kinds of themes help, and how we should blend what members tell us with our existing personalization systems.
  • What tradeoffs does this technology bring? How cost and latency hold up in production as we ramp traffic, how long members will wait for generated results, and whether errors came from the model, the harness or our existing systems. Multi-turn sessions also need different evaluation and observability than single requests.

Longer term, our goal is a system that improves itself, starting from the record each request leaves behind. Today we replay past requests against a new prompt, model or rule to see what changes, and we judge each change with automated checks, LLM judges and human evaluations. Eventually, we want the system to propose improvements, test them safely and keep only what proves better, within our privacy and data-use policies. As LLMs improve, more of the work may move into them, and the intelligence layer lets us move that line deliberately.

This is part of a bigger shift. Recommendation systems have long learned quietly from what members watch and answered with ranked rows. LLMs let them listen and respond, and members may increasingly expect that. We’ll keep exploring what that means for discovery on Netflix.

Acknowledgements

We would like to thank Adi Suresh, Akash Katipally, Allan Johns, Becks Wood, Bhargav Mangipudi, Carrie Santiago, Chris Martin, Claire Campbell, Corey Waldin, Dana Sittler, Daneo Zhang, David Leen, Devon Bryant, Dharamendra Kumar, Dharini Chandrasekaran, Ebony Turner, Federico Roa, Gianfranco Cuoco, Guru Tahasildar, Haley Clanton, Haresh Chudgar, Ivan Provalov, James Schultz, JingXu Yang, Josie Shaw, Kamelia Aryafar, Kate Cummings, Kathleen Garrity, Kelley Robinson, Kevin Du, Kevin O’Connor, Kyla Moore, Kyle Lind, Laura Matsuura, Leah Cusella, Lingyi Liu, Lingyong Wang, Mallory Walkup, Matthew Pereira, Michael Galassi, Minsu Jang, Moumita Bhattacharya, Paran Jain, Paul Lee, Qusai Al-Rabadi, Scarlet Chen, Sergi Perez, Sriram Rao, Stephen Shaw, Sura Elamurugu, Varad Pathak, Yesu Feng, Zainab Mahar Mir, and Zhongli Cheng for their contributions to this work.


Engineering AI Discover was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Redict deprecated in favor of Valkey

Post Syndicated from daroc original https://lwn.net/Articles/1108155/

Drew DeVault has
announced that
Redict, a fork of Redis that was created in response to
Redis’s 2024 license change, has been deprecated. He recommends switching to Valkey, the permissively licensed Redis fork supported by the Linux Foundation. The two projects are mutually compatible, so switching should be as simple as changing which package is installed and renaming the configuration file.

I had hoped to rally the Redis diaspora around a copyleft initiative, to protect ourselves from future rug-pulls, and made Redict to serve this purpose. However, with the valkey project’s success, and Redis’s return to a copyleft license, Redict was not able to build a sustainable community.

We recommend that Redict users switch to valkey, which uses a permissive license but has better long-term prospects. We advise against switching back to Redis; though it is once again open source, and copyleft, it uses a contributor license agreement which will facilitate another rug-pull when Redis has a bad financial quarter.

How Rakbank built centralized observability at scale with Amazon OpenSearch Service

Post Syndicated from Georges Hamieh original https://aws.amazon.com/blogs/architecture/how-rakbank-built-centralized-observability-at-scale-with-amazon-opensearch-service/

In this post, we discuss how Rakbank retail digital banking platform ingests approximately 150 GB a day of telemetry across a cross-account, Multi-Availability Zone (Multi-AZ) Amazon OpenSearch Service design, with hot/warm/cold tiering, 7-year compliance retention backed by Amazon Simple Storage Service (Amazon S3), and approximately 55 percent cost savings over an all-hot cluster.

Context and workload profile

Rakbank’s retail digital banking platform runs as containerized microservices on Amazon Elastic Kubernetes Service (Amazon EKS), and its observability requirements are driven by a few hard numbers. The platform now generates roughly 150 GB of logs per day on average, up from about 5 GB/day before the migration. That produces around 9 TB retained in OpenSearch Service over a 60-day window (150 GB/day × 60 days), with the most recent 30 days directly searchable. Retention runs to seven years for compliance, aligned with Central Bank of the UAE (CBUAE) requirements and Rakbank’s internal data-retention policy. At an average of 150 GB per day, that archives approximately 54 TB of log data per year, or approximately 383 TB over seven years. On the consumption side, 25 dashboards serve about 25 concurrent users. The data itself has an important property: logs are append-only. After written, a log document is never updated or deleted, so there is no update or delete-by-query churn. (Where regulatory write-once-read-many immutability is required, the S3 archive bucket can enforce it with Amazon S3 Object Lock.)

The append-only pattern is architecturally significant: because indices are no longer written to once they roll over, force-merging them to a single segment per shard before warm migration is safe, and there is no update overhead as indices roll down the tiers.

Telemetry pipeline: Fluent Bit

Instrumentation follows an instrument once, standardize everywhere model on a Fluent Bit standard across all banking domains (retail, business, wholesale). Concretely:

  • Fluent Bit runs as a DaemonSet on the EKS cluster, tailing container stdout/stderr on each node and enriching records with Kubernetes metadata (pod, namespace, labels) before routing.
  • Fluent Bit performs a dual-write/parallel archive: one path ships to the OpenSearch Service ingest endpoint (hot), a parallel path lands raw log objects directly in Amazon Simple Storage Service (Amazon S3) for durable backup independent of the search tier.

Cross-account topology and private connectivity

The design separates the workload from its observability plane using two accounts:

Application account

  • Amazon EKS cluster running the app pods in the Application virtual private cloud (VPC).
  • Fluent Bit DaemonSet for container-log collection and routing.
  • A parallel archive path to Amazon S3 (Log Archive & Backup).

Observability account

  • A dedicated OpenSearch Service centralized logging domain in the OpenSearch Service VPC, spanning three Availability Zones.
  • OpenSearch Service Dashboards as the access/visualization layer, routed to the hot data nodes.

Connectivity. Cross-account log flow traverses an AWS Transit Gateway, keeping all communication private within AWS. No traffic egresses to the public internet. In practice, Transit Gateway route tables provide reachability between the application and OpenSearch Service VPCs. Access is scoped at the VPC boundary by security groups and network ACLs that permit only the required ingest traffic (HTTPS/443) to the domain.

The following diagram shows the full cross-account path: application pods write logs through a Fluent Bit DaemonSet, which both forwards them privately over AWS Transit Gateway to the OpenSearch Service domain and archives a parallel copy to Amazon S3.

Cross-account architecture showing Amazon EKS pods sending logs through Fluent Bit over AWS Transit Gateway to a Multi-AZ OpenSearch Service domain with Amazon S3 archival

Figure 1: Centralized observability platform showing cross-account log flow from the EKS application account across AWS Transit Gateway into the Multi-AZ OpenSearch Service domain with hot, UltraWarm, and cold tiering and Amazon S3 archival

In the Application account, three application pods on the Amazon EKS cluster write logs that a Fluent Bit DaemonSet collects. Fluent Bit ships one copy over AWS Transit Gateway to the Observability account and archives a parallel copy to the Amazon S3 Log Archive and Backup bucket. In the Observability account, the OpenSearch Service centralized logging domain spans three Availability Zones. Each zone has a dedicated cluster-manager node (m8g.large.search) and a hot data node (m8g.2xlarge.search) that ages out to an UltraWarm node (ultrawarm1.medium.search) and then to a shared, node-free S3-backed cold storage tier. OpenSearch Service Dashboards reads from the hot data nodes for visualization.

Identity and cross-account authorization flow

The platform spans two accounts, with access governed by the layered security model of OpenSearch Service: network isolation (VPC and private Transit Gateway connectivity), the domain’s resource-based access policy, and fine-grained access control (FGAC) on the VPC domain. End users reach OpenSearch Service Dashboards through Security Assertion Markup Language (SAML) 2.0 single sign-on federated to Rakbank’s corporate Active Directory. Access follows existing enterprise identities and group memberships, with no separate OpenSearch Service credentials. Log ingestion from the application account is authorized separately from user access, keeping the write path and the read path on distinct, least-privilege roles. Together these layers keep all telemetry flowing privately within AWS while access stays centrally governed in Active Directory.

Cluster topology (per-AZ node roles)

The domain is a 3-AZ deployment with dedicated cluster-manager nodes separated from data nodes:

Role Per-AZ instance Count Purpose
Cluster manager m8g.large.search 3 (1/AZ) Cluster state, shard allocation, no data
Hot data node m8g.2xlarge.search 3 (1/AZ) Active indexing + real-time query
UltraWarm node ultrawarm1.medium.search 3 (1/AZ) Read-only, S3-backed warm segments
Cold tier No nodes — Detached S3-backed storage, managed by OpenSearch Service

The hot data and cluster-manager nodes are Graviton (m8g) for better price/performance. Dedicated cluster-manager nodes isolate cluster-state management from indexing and query load, which matters after you’re pushing 150 GB/day through the hot tier.

Storage tiering: right data · right store · right cost

The core mechanism is OpenSearch Service multi-tier storage, with indices aging through tiers using Index State Management (ISM) policies keyed off index age:

Tier Backing Retention Access pattern Instance/store
Hot Amazon Elastic Block Store (Amazon EBS) (gp3) volumes on data nodes 0–15 days Real-time dashboards, active troubleshooting, alerting m8g.2xlarge.search
Warm (UltraWarm) Amazon S3 + local cache 15–30 days Read-only historical analysis. Cost-optimized, still fully searchable ultrawarm1.medium.search
Cold Amazon S3 (detached, no nodes) 30–60 days Older logs for on-demand investigation. Attach to UltraWarm when needed S3-backed, 0 compute at rest

How the lifecycle behaves:

  • Hot → UltraWarm: ISM transitions indices at approximately 15 days. UltraWarm keeps primary shard data in S3 while caching hot blocks locally, so queries still run, only at higher latency and far lower cost per GB. Because rolled-over indices are no longer written to, they are force-merged before migration for faster warm-tier read performance.
  • UltraWarm → Cold: At approximately 30 days, indices detach to the cold tier, which is pure S3 storage with no dedicated compute. Cold indices are not directly searchable: to query them, you selectively attach them back to UltraWarm nodes on demand. (Querying the raw S3 archive without reattaching is a separate path that uses Amazon Athena.)
  • Compliance archive (S3 + Athena): Everything also lands in a separate Amazon S3 bucket for the full 7-year window, and is queried with Amazon Athena, at the lowest cost per GB. This decouples how long data must be kept from how much hot compute is paid for.

Durability details called out in the design: The durability of Amazon S3 means the design can run 0 replicas on the warm/cold tiers and remain durable (S3 handles redundancy), which further cuts cost. UltraWarm is a read-only warm tier, and Graviton (m8g) powers the hot and cluster-manager nodes.

Alerting. Hot-tier data drives OpenSearch Service alerting with email and Microsoft Teams destinations for real-time operational alarms.

Production sizing and cost model

Sizing target: 150 GB/day average, 60-day retention (30 days directly searchable) (the cluster is provisioned with headroom for an approximately 200 GB/day peak, which is the basis for the node sizing that follows). Rakbank evaluated two topologies:

Option 1 — Hot + UltraWarm (recommended)

  • 3 × m8g.2xlarge hot data nodes.
  • 3 × ultrawarm1.medium.search + cold tier.
  • 3 × m8g.large dedicated cluster-manager nodes.
  • Approximately 55 percent savings compared to all-hot.

Option 2 — All Hot

  • 3 × r8g.4xlarge, approximately 8,320 GB each.
  • 3 × m8g.large admin, no warm tier.
  • Higher cost, all data resident hot.

Pricing is On-Demand. Reserved Instances reduce it further. The takeaway: for a 9 TB, 60-day window, the bulk of data is rarely queried after the first couple of weeks. Pushing older indices to an S3-backed warm/cold tier removes the need to keep the full working set on hot r8g nodes, which is where the approximately 55 percent delta comes from.

Scaling the observability architecture with OpenSearch Service

As the platform grew from approximately 5 GB/day to approximately 150 GB/day with 25 dashboards and approximately 25 concurrent users, the observability architecture had to meet three requirements:

Predictable cost at high ingestion volume, repeated dashboard queries without per-query cost coupling, and multi-tier retention spanning real-time access through to 7-year archival. OpenSearch Service meets these requirements with an instance-based model and hot/warm/cold tiering: ingestion and queries run on provisioned capacity, and older indices age into S3-backed tiers for long-term retention at a low cost per GB. This gives Rakbank a predictable, capacity-based cost model as data volume and dashboard usage grow.

Resilience: Multi-AZ and the Standby trade-off

Deployment option SLA Failover Nodes
Multi-AZ (no Standby) 99.9% out-of-the-box automatic 3 AZ · 3 data nodes + 3 dedicated cluster-manager nodes
Multi-AZ with Standby 99.99% < 1 min automatic on AZ failure 3 AZ · 2 data active + 1 standby

The trade-off to understand: with Multi-AZ with Standby enabled, only two of three data nodes serve search requests. The third is reserved for failover. That is a 33 percent reduction in active search capacity in exchange for the higher service level agreement (SLA). Standby also requires at least two replicas per index, which increases storage, and is supported only on specific instance families, so check the current list before planning it. If a 99.99 percent SLA is not a hard requirement, running without Standby keeps all data nodes serving search. Rakbank runs its production domain without Standby, with data nodes across all three Availability Zones and replica shards for redundancy.

AI-powered observability capabilities

Rakbank is evaluating newer, machine learning (ML) and agent-driven features of OpenSearch Service that can layer on top of the tiered store:

  • AI Assistant – Natural-language → query generation (for example, “Show error spikes in the last 24h”), backed by Amazon Bedrock.
  • MCP Server + Agent investigator – DevOps agents autonomously execute PPL queries for root-cause analysis. A Memory Store provides persistent context across agent conversations.
  • Direct Query – Query Amazon S3 data without ingesting it into OpenSearch Service, an option alongside Amazon Athena for the S3 archive.
  • Trace Correlation – Available as trace collection is added to the pipeline: unify logs, traces, and metrics in one view, with automatic trace/log correlation and service maps.
  • Query surface – PPL, DSL, SQL, PromQL. Integrates with Amazon Managed Service for Prometheus and Amazon OpenSearch Ingestion for high-performance ingest.

Outcomes

Running on the Fluent Bit standard, the platform now serves three audiences from a single pane of glass. Support operations get faster triage and guided troubleshooting, engineering teams use it for root-cause analysis and debugging across the request path, and the business gains journey trends and actionable insights.

Net results: lower mean time to resolution (MTTR), higher reliability, data-driven insights, and improved operational efficiency. In their own environment, Rakbank measured faster performance after upgrading across OpenSearch Service versions (1.3 → current), with single-digit-millisecond latencies for lexical and vector queries.

Engineering lessons learned

  1. Multi-tier from day one – Design hot/warm/cold up front. Retrofitting tiering onto a live 150 GB/day cluster is significantly harder than starting with ISM policies in place.
  2. Size for peak, not today – Ingestion grows as more microservices come online. Provision headroom in the hot tier and shard count.
  3. Model the Standby trade-off explicitly – 99.99 percent costs you 33 percent of active search capacity and requires two replicas per index. Decide per workload whether that SLA is worth it.
  4. Exploit the append-only advantage – Append-only logs are the recommended candidate for multi-tier storage: no update overhead, clean force-merge before warm migration, and predictable rollover.


About the authors

Georges Hamieh

Georges Hamieh

Georges is a Senior Technical Account Manager at AWS. He supports FSI customers across the Middle East and North Africa in building scalable and intelligent cloud solutions.

Tapas Kumar Mondal

Tapas Kumar Mondal

Tapas is the Executive Vice President & Chief Technology Officer in Digital & AI at Rakbank. He heads Rakbank architecture, design, and technology strategy, and is the CTO for digital channels and AI platforms.

Amit Pareek

Amit Pareek

Amit is a Senior Vice President and Enterprise architect in Archtecture, Design & Strategy at Rakbank. He leads the solution architecture practice at Rakbank.

Chandramouli Pitchaiyappan

Chandramouli is a Cloud Solution Architect – Architecture, Design and Strategy at Rakbank. He designs and runs Rakbank’s AWS platforms, focusing on Amazon EKS, observability at scale and cloud cost optimization.

[$] Zellij manages terminal workspaces with style

Post Syndicated from jzb original https://lwn.net/Articles/1106913/

Zellij is a relatively new entrant in the
terminal-multiplexer
category. Like GNU
Screen
and tmux it gives
users the ability to manage a workspace inside a terminal with split panes,
provides session management, and so forth; but Zellij also includes a web server for
browser access to a terminal session, is extensible via a plugin API, and is likely
more beginner-friendly than its predecessors. Its most recent release, version 0.46,
adds a standalone terminal emulator, a built-in inbox for notifications, and a settings
screen so users can configure the application without fussing with
configuration files. While the low version number might suggest that it is not
yet ready for serious use, it seems stable and full-featured enough to
meet the needs of many users.

Who Has Access to Claude? Bring AI Identity and Access Context Into Surface Command

Post Syndicated from Rapid7 original https://www.rapid7.com/blog/post/em-claude-access-brings-ai-context-into-surface-command-asm-easm

Approving an AI service is only the starting point. As employees adopt Claude and their responsibilities change, security teams need to know who has access, which users hold administrative privileges, and whether those roles and group memberships still reflect the work they do.

IBM’s 2025 Cost of a Data Breach Report found that, among studied organizations reporting an AI-related breach, 97% lacked proper AI access controls. The finding highlights a broader challenge: AI adoption needs security practices that extend beyond the initial approval, supported by information teams can use to review access with administrators and service owners.

Rapid7 Surface Command now integrates with Claude’s Compliance API, bringing supported organization, user, role, group, and settings information into the same platform teams use to understand other assets and identities. The integration helps security teams make enterprise Claude access part of their existing review practices.

Bring enterprise AI access into your security view

An account list tells security teams who is present, while roles and group memberships help explain how access is organized and where further review may be needed. Surface Command’s integration with Claude’s Compliance API brings together:

  • Organizations and users: Visibility into the Claude organization and its associated user accounts.

  • Roles and groups: Context to understand users’ assigned roles and group memberships.

  • Organizational settings: Available configuration information to support review of the enterprise Claude environment.

With those details in Surface Command, practitioners can examine Claude identities alongside the other assets and identities they manage. That gives them a clearer basis for working with service owners to evaluate whether access remains appropriate as teams and responsibilities change.

The integration focuses on administrative visibility. It does not ingest Claude conversation content, provide threat detection on Claude activity, or control Claude’s behavior.

From a user record to an informed access review

Consider a security practitioner reviewing administrative access to Claude. In Surface Command, they can inspect an imported user’s details, review their organization role and administrative status, and examine their group memberships. The relationship graph provides a visual view of how that user connects to the organization and its groups, making those associations easier to follow.

image1.png

The practitioner can then work with the service owner to confirm whether administrative privileges are still needed, whether group memberships reflect current responsibilities, and whether those assignments align with the organization’s access model.

Surface Command provides information to support the review, while the team applies its policies and judgment to determine whether a change is needed.

image2.png

Support AI adoption with clearer accountability

As Claude becomes part of everyday work, reviewing its users and access relationships becomes part of managing the environment. Bringing that information into Surface Command helps security practitioners and service owners work from a shared understanding of assigned roles and group memberships. It supports more informed access decisions and helps security leaders incorporate enterprise AI into established oversight practices.

Get started with Claude and Surface Command today

The integration is available through the Anthropic connector in the Rapid7 Extension Library. Using Claude’s Compliance API requires a Compliance API key and the appropriate entitlement for your Claude organization.

Visit the connector page to get started and see how Surface Command brings Claude users, roles, and group relationships into view.

Security updates for Tuesday

Post Syndicated from jzb original https://lwn.net/Articles/1108140/

Security updates have been issued by AlmaLinux (.NET 10.0, .NET 11.0, .NET 8.0, .NET 9.0, bind, bind9.18, buildah, c-ares, cjose, cockpit, cockpit-files, cockpit-machines, cockpit-podman, containernetworking-plugins, crun, delve, dhcp, dogtag-pki, dovecot, dpdk, edk2, emacs, environment-modules, expat, fetchmail, firefox, flatpak, flatpak-builder, freerdp, gcc, gcc-toolset-15-gcc, gcc-toolset-16-gcc, git-lfs, glib2, glibc, glycin-loaders, gnome-remote-desktop, go-fdo-client, go-fdo-server, grafana, grafana-pcp, gstreamer1, gstreamer1-plugins-bad-free, gstreamer1-plugins-base, guava, gvfs, gvisor-tap-vsock, ignition, iperf3, java-1.8.0-openjdk, jq, kernel, librabbitmq, libreswan, librsvg2, libsoup, libsoup3, libX11, libXi, libxml2, libXrender, libXtst, lrzsz, microcode_ctl, mingw-glib2, mod_auth_openidc, mod_http2, NetworkManager, nginx, nginx:1.24, nginx:1.26, nodejs:24, nodejs:26, oci-seccomp-bpf-hook, openexr, openssh, openssl, pcp, perl-DBI, perl-DBI:1.641, perl-URI, php:8.4, podman, polkit, postgresql:16, python-jwcrypto, python-oauthlib, python-tornado, python3, python3.12, python3.9, rpm, rsyslog, runc, rust-sequoia-sq, sos, squid, sssd, tesseract, tftp, tomcat, tomcat9, unbound, util-linux, webkit2gtk3, wireshark, xdg-dbus-proxy, xfsprogs, xorg-x11-server, xz, and yggdrasil), Debian (gnocchi, kernel, lightdm, roundcube, zaqar, and znc), Fedora (assimp, chromium, criu, freerdp, maturin, mysql8.4, perl-Catalyst-Plugin-Authentication, python-jiter, python-pymdown-extensions, python-pysequoia, qtox, ruff, rust-afterburn, rust-astral_async_zip, rust-clearscreen, rust-coreutils, rust-jiter, rust-lzma-rust2, rust-mailparse, rust-pyo3-introspection, rust-python-pkginfo, rust-sccache, rust-serde_json, rust-testresult, rust-zip, selenium-manager, tpm2-tss, ty, and xfsprogs), SUSE (apache2, azure-storage-azcopy, container-suseconnect, containerd, crane, dpdk, ghostscript, google-cloud-sap-agent, google-osconfig-agent, govulncheck-vulndb, graphifyy, hauler, helm, helm3, hivex, java-21-openjdk, java-25-openjdk, libevent-2_1-7, libmikmod-devel, libXi, mtools, nodejs24, open-iscsi, parted, podman, psqlODBC, python-M2Crypto, python-tornado6, python3, re2c, rsyslog, speex, thunderbird, valkey, vsftpd, and zbar), and Ubuntu (buildstream, cairosvg, commons-configuration2, deluge, dokuwiki, eterm, gnupg1, groovy, gst-plugins-bad1.0, gst-plugins-base1.0, h2o, htmldoc, net-snmp, netkit-rsh, node-moment, openjdk-25-crac, pdfresurrect, pillow, postsrsd, psensor, rlottie, sos, sosreport, vim-syntastic, yadifa, zbar, and zutils).

Formal Verification of the Signal Protocol Using AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/11/formal-verification-of-the-signal-protocol-using-ai.html

This seems like a good thing:

Google Deepmind researchers used agentic AI to mathematically prove, or “formally verify,” a number of the Signal protocol’s key cryptographic guarantees­a landmark development for the widely used cryptography and AI itself.

Conducted as a sort of proof-of-concept project in just four weeks, the work is significant in two ways. It serves as further independent validation of the cryptography that protects massive quantities of the world’s communications on platforms like the Signal app, Google Messages, and WhatsApp. And it demonstrates Google DeepMind’s formal verification capabilities using a new AI framework called AlphaProof Code.

[…]

The DeepMind analysis did not find any new vulnerabilities in the portions of the Signal protocol it looked at, but when the researchers used AlphaProof Code on older versions of Signal that contain known and long-fixed vulnerabilities, it correctly identified them and showed that the protocol could not be formally verified. The researchers are releasing the specification and proof they developed for the Signal protocol analysis to aid other formal verification work.

Alternate link.

Details:

First, our researchers collaborated with a mix of models to translate Signal’s security goals into formal mathematical specifications, with human experts reviewing every one. From there, agents powered by Gemini Carbon did the proofs, generating over six million lines of Lean, a computer language that mathematically proves the accuracy of code.

Next, the agents audited the proof and highlighted areas that needed a second look by a human ­ just one percent of the codebase, a massive time savings. Because Lean automatically checks the rest, our experts could focus their review where human judgment matters most.

Technical paper.

NVIDIA and Lambda Disclose First Production Co-Packaged Optics Cluster… It is FINALLY real

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/nvidia-and-lambda-disclose-first-production-co-packaged-optics-cluster-it-is-finally-real/

Lambda is the first to disclose it has co-packaged optics deployed in a production cluster with over 10,000 GPUs

The post NVIDIA and Lambda Disclose First Production Co-Packaged Optics Cluster… It is FINALLY real appeared first on ServeTheHome.

Deliver petabytes of Apache Kafka data to Amazon S3 at up to 60% lower cost with Amazon MSK Express brokers

Post Syndicated from Diksha Dubey original https://aws.amazon.com/blogs/big-data/deliver-petabytes-of-apache-kafka-data-to-amazon-s3-at-up-to-60-lower-cost-with-amazon-msk-express-brokers/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers deliver Apache Kafka topic data to general purpose Amazon Simple Storage Service (Amazon S3) buckets at lower cost and without the operational overhead of running Kafka Connect. Because Express brokers handle both ingestion and delivery, you can reduce your ingestion and delivery costs by up to 60% compared to self-managed alternatives. There is no connector or infrastructure to manage, you pay only for the data delivered, and delivery doesn’t consume broker throughput.

Many Kafka workloads need a durable copy at rest in Amazon S3 for backup and archive. Compliance rules often require you to keep raw events for years for audits. You require a replayable copy that outlives topic retention, raw training data for artificial intelligence and machine learning (AI/ML) models, and a staging area for scheduled extract, transform, and load (ETL) jobs. For analytics, Express brokers also deliver to streaming tables, which continuously materialize your Kafka topics as Apache Iceberg tables on Amazon S3 Tables, a capability of Amazon S3, with no Kafka connectors, Apache Flink jobs, or custom consumers to run. The tables are registered automatically in AWS Glue Data Catalog, so you can query them with Amazon Athena, Amazon Redshift, and Apache Spark, and inline compaction reduces downstream query costs by up to 30%. Because delivery doesn’t add broker load, one topic can feed both an S3 bucket and a streaming table. For more information, see Deliver Apache Kafka data to streaming tables for Apache Iceberg with Amazon MSK Express brokers.

In this post, we look at the two challenges of delivering Kafka data to Amazon S3 today, managing Kafka brokers and managing the delivery pipeline, and how Express brokers and data delivery to Amazon S3 address each one. We then walk through the architecture and show how to get started on the console and with Agent Skills.

Challenges with delivering streaming data to Amazon S3 on self-managed Kafka

To deliver Kafka data to Amazon S3 today, you typically run an S3 sink connector on Kafka Connect next to your Kafka cluster. That leaves you with two systems to run:

Managing Kafka brokers: You size and provision broker storage upfront, monitor its utilization to avoid disruptions, and keep paying for it even if your workload scales down. You recover failed brokers, manage Kafka configurations for availability and performance, and patch brokers during maintenance windows. Adding capacity means provisioning brokers and rebalancing partitions, which can take hours or days, so you size the cluster for peak traffic and plan scaling well ahead.

Managing the delivery pipeline: Running Kafka Connect typically causes the following three challenges:

  • Operational complexity: You find or build a connector, take it through security approval, deploy it, and apply security updates across your Kafka Connect workers. When delivery fails, you troubleshoot across brokers, workers, and Amazon S3.
  • Cost: You size Kafka Connect workers for peak demand and keep paying for it when traffic is low, and a pipeline assembled from several services adds a charge at every hop.
  • Contention with real-time consumers: A connector reading from a Kafka topic consumes broker egress throughput, so feeding the archive competes with your real-time applications. Cluster scaling and version upgrades can also interrupt delivery.

How Express brokers and data delivery to Amazon S3 address these challenges

Managing Kafka brokers: Express brokers include pay-as-you-go storage that scales automatically, so there’s no storage to size, provision, or monitor. When your workload scales down, the cluster uses less storage and your storage charges go down automatically. MSK recovers failed brokers for you, manages critical cluster and topic configurations for availability and performance on your behalf, and updates cluster hardware on an ongoing basis with no maintenance windows. To add capacity, you add brokers, and Express rebalances partitions onto them in minutes, so you don’t need to over-provision for traffic spikes or plan scaling far ahead. For details, see Simplifying Kafka operations with Amazon MSK Express brokers. To move from self-managed or third-party Kafka, Amazon MSK Replicator copies your data and consumer group offsets into an Express cluster, and the migrate-to-msk Agent Skill recommends a right-sized Express cluster before you start. For more information, see Migrate Kafka workloads to an Amazon MSK cluster.

Managing the delivery pipeline: Data delivery to Amazon S3 is built into Express brokers, so there’s no Kafka Connect to run. You create a channel on a topic, and MSK runs the delivery. This addresses each of the three challenges:

  • Operational complexity: There’s no connector to find, build, or take through security approval, nothing to deploy beyond the channel, and no workers to patch. MSK handles retries and backpressure. When a record can’t be processed, the channel writes its identifiers and error context to a dead-letter queue (DLQ) bucket and delivery continues, and you troubleshoot in one place, through the channel’s Amazon CloudWatch metrics and logs.
  • Cost: There’s no capacity to size for peak, because MSK scales delivery with your workload. You pay only for the data delivered, billed per byte, so you pay less when traffic is low. Delivery adds one charge on top of standard Amazon S3 charges, with no connector or worker fees, no charge for the broker egress that delivery uses, and no charge for records routed to the DLQ.
  • Contention with real-time consumers: The channel reads the topic without consuming broker throughput, so archiving doesn’t compete with your real-time applications, and you can add channels to a topic without adding broker load. Capacity scaling and version upgrades happen without delivery gaps.

MSK data delivery to Amazon S3 architecture

Producers write to a Kafka topic exactly as they do today. The channel reads records from the topic, batches them, and writes them as objects to your S3 bucket. You choose the compression (NONE, GZIP, or ZSTD), the storage class (S3 Standard, S3 Intelligent-Tiering, or S3 Glacier Instant Retrieval), and an output key template that defines the object key layout, such as date-based prefixes with the partition and offset in each object name. Records keep the format the producer wrote them in, whether JSON, UTF-8 strings, or raw bytes, and no schema registry is required.

For JSON and String records, the channel validates each record. If a record fails validation, the channel writes the record’s identifiers and the error context to the DLQ bucket in Amazon S3, and delivery continues. You can also send delivery logs to Amazon CloudWatch Logs, Amazon S3, or Amazon Data Firehose.

The following diagram illustrates this architecture.

Architecture diagram of Amazon MSK Express brokers delivering a Kafka topic to a general purpose S3 bucket and to Apache Iceberg streaming tables on Amazon S3 Tables

Figure 1: Producers publish to a Kafka topic on Amazon MSK Express brokers. Data delivery writes the topic to a general purpose S3 bucket as objects in their source format, which you can use for backup and archival, compliance retention, replay beyond topic retention, AI/ML model training, and scheduled ETL jobs. Streaming tables write the same topic to Apache Iceberg tables on Amazon S3 Tables, registered in AWS Glue Data Catalog, so you can bring your own engine for query and analytics, such as Amazon Athena, Amazon Redshift, Apache Spark on Amazon EMR, or AI agents built with Amazon Bedrock. No connector runs between the cluster and Amazon S3

Before you plan your deployment, review Requirements and supported configurations in the Amazon MSK Developer Guide for supported Regions, accounts, and configurations.

Getting started

To get started, open the Amazon MSK console, choose your Express broker cluster, and create a channel on the Channel tab with data delivery to general purpose S3 as the destination type. For step-by-step instructions, see Create your first Channel. Before you deploy to production, review the prerequisites, supported configurations, service execution role, output key template, and recommended alarms in the Amazon MSK Developer Guide.

If you’re moving from an existing connector, create the channel before you retire the connector, and keep both running until you confirm that the delivered data overlaps.

You can also manage channels with the Amazon MSK APIs and the AWS Command Line Interface (AWS CLI) (for example, aws kafka create-channel) through infrastructure as code or automation across many clusters and topics, or let an AI agent do it for you, as the next section shows.

Getting started with Agent Skills

AWS publishes open source Agent Skills, available through the Agent Toolkit for AWS, that give AI coding agents guidance for configuring delivery on services. The managing-amazon-msk skill covers data delivery to Amazon S3 on an Express broker cluster. The skills guide your agent through the setup steps that are easy to get wrong: the IAM role and trust policy, output key template rules, DLQ setup, and verifying delivery after the channel is running.

Installing as an Agent Skill

Skills are discovered automatically by compatible tools through the SKILL.md file. Follow the Agent Toolkit installation guide, then add the skill for the service you are working with:

aws configure agent-toolkit
aws agent-toolkit add-skill --skill-name managing-amazon-msk

We also recommend installing the AWS MCP Server, which gives your agent tools for searching AWS documentation, blogs, and Skills dynamically at runtime. This makes both discovery and installation more flexible, and the agent itself more accurate. To verify the installation, interact with the skill in your preferred tool.

To begin delivery, prompt your agent of choice. For Amazon MSK, “Set up data delivery from my orders topic to my archive bucket”:

Screenshot of an agent chat with a prompt to set up data delivery from a topic to an archive bucket

Figure 2: Issuing the delivery prompt in an agent chat

The agent first dynamically loads the relevant skill, inventories the clusters, topics, and buckets available in your account. It then confirms the resources to use or create before creating the delivery configuration. After creation, the agent summarizes the status and can help with the data operations that follow, such as setting up an AWS Glue crawler so the delivered objects are queryable as partitioned tables in Amazon Athena, or configuring CloudWatch alarms on delivery freshness and dead-letter queue activity.

Screenshot of the agent reporting that it created the delivery channel

Figure 3: The agent creates the channel

Clean up

To avoid ongoing charges, delete the resources you created for this walkthrough. An active channel keeps delivering records and incurring delivery charges until you delete it. On Amazon MSK, open your cluster in the Amazon MSK console, choose the Channel tab, and delete the channel. Objects already written to Amazon S3 keep incurring storage charges after the channel is deleted, so delete the delivered objects, and the destination and DLQ buckets if you no longer need them. Finally, delete the IAM service execution role and any CloudWatch log groups created for the channel, including any that your agent created.

Conclusion

With data delivery to Amazon S3 on Amazon MSK, you can keep a durable copy of your streaming data in Amazon S3 without running a connector. You pay only for data that is delivered, and delivery doesn’t compete with your real-time consumers for throughput.

To learn more, see Amazon MSK data delivery to Amazon S3 in the Amazon MSK Developer Guide. For pricing, see Amazon MSK pricing. If you want to query your streaming data as Apache Iceberg tables instead of raw objects, see Deliver Apache Kafka data to streaming tables for Apache Iceberg with Amazon MSK Express brokers.


About the authors

Diksha Dubey

Diksha Dubey

Diksha is a Senior Product Manager for Amazon MSK. She works with customers to run Apache Kafka at scale and turn their real-time data into files and tables that analytics engines and AI agents can use. Working backwards from their needs, she shapes how Amazon MSK gets streaming data to where customers use it, starting with Amazon S3 and Apache Iceberg tables. Her focus is on making Kafka data easy to store, query, and share across teams, without pipelines to build or run.

Subham Rakshit

Subham Rakshit

Subham is a Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughters.

How British Airways is accelerating the modernization of its Java services

Post Syndicated from Shane Routley original https://aws.amazon.com/blogs/devops/how-british-airways-is-accelerating-the-modernization-of-its-java-services/

At British Airways (BA), engineering at scale means supporting services used across the airline for millions of passengers, while simultaneously preparing for what comes next. After completing a major migration of legacy data center infrastructure to AWS, the next question was how BA could use its new cloud capabilities to improve scalability and efficiency. The team also wanted to accelerate the next phase of modernization.

As part of this next phase, BA began exploring how agentic AI could help accelerate the modernization of its technology estate. Working with AWS, the team identified AWS Transform custom as a way to support this at scale. This purpose-built solution is designed to modernize large legacy platforms using agentic AI and automation. The first major target was a legacy Java platform of more than 250 business services across around 750 code repositories. BA set out to migrate it from Amazon Elastic Compute Cloud (Amazon EC2) to a modern, cloud-native architecture on Amazon Elastic Container Service (Amazon ECS) with AWS Fargate and AWS Graviton. The new architecture is containerized, auto scaling, and resilient by design.

About British Airways

British Airways is the UK’s flag carrier airline, serving more than 40 million customers annually across more than 200 destinations worldwide, and a subsidiary of International Airlines Group (IAG).

Challenge

British Airways’ Java platform had supported the airline for many years, but maintaining and updating it required valuable engineering time that could be more efficiently spent advancing innovation. As BA continued to modernize its technology foundations, the team identified an opportunity to move services to a more scalable architecture and simplify their ongoing management.

“Can AI really transform hundreds of code repositories at enterprise scale? That was the question everyone asked when we started this journey. With more than 250 business services on a legacy platform, maintaining the estate demanded considerable engineering time. We needed a more efficient approach that would free our teams to focus on innovation rather than routine maintenance.”

— Gary Holland, Principal Platform Architect at British Airways

Solution

British Airways partnered with AWS to deploy AWS Transform custom, purpose-built to modernize large legacy estates using agentic AI and automation. Starting with an Experience Based Acceleration (EBA) using Amazon Q Developer, the team moved swiftly. When AWS Transform custom launched at AWS re:Invent 2025, BA was among the first to build with it. Its first fully transformed service went live in production shortly after.

How the transformation engine works

Each service passes through a 20-step transformation lifecycle that blends deterministic automation with agentic AI, designed to be repeatable across hundreds of services without manual re-engineering.

Diagram of the 20-step British Airways transformation lifecycle in three phases. Phase 1, deterministic preparation with GitHub Actions: 1 identify the live service version in GitHub, 2 determine non-functional and observability requirements, 3 run baseline regression tests, 4 run baseline non-functional tests, 5 identify required data sources, 6 create infrastructure, 7 copy, branch, and wire up the service. Phase 2, agentic transformation: 8 run AWS Transform custom to transform the code, including the upgrade to Java 21 and the move from Amazon EC2 to Amazon ECS on AWS Fargate with Graviton, 9 check for hard-coded version numbers, 10 push the transformed code to GitHub. Phase 3, deterministic testing and deployment: 11 build and deploy, 12 update API gateway routing to Amazon ECS, 13 run automated regression test packs, 14 compare results against the baseline, 15 code review, 16 security and code quality scanning, 17 service operations review, 18 cybersecurity approval, 19 support handover, 20 go-live.

Figure 1: The 20-step transformation lifecycle British Airways uses with AWS Transform custom

Phase 1: Deterministic preparation. GitHub Actions workflows analyze each service repository to identify the production-versioned artifact currently deployed, then catalog its dependencies and data source configurations. Automation runs against live production logs to extract peak and mean traffic rates. It then infers the non-functional requirements (scaling thresholds, resource sizing, and observability settings) needed to configure each service’s new container on Amazon ECS. Baseline regression and performance test packs are executed against the existing platform to establish a known-good benchmark before any code is touched. The infrastructure for each service is then created, and the service code is copied, branched, and wired up, ready for transformation.

Phase 2: Agentic transformation. AWS Transform custom transforms the codebase for the target architecture. This includes upgrading to Java 21 and migrating from Amazon EC2 deployment patterns to Amazon ECS on AWS Fargate with Graviton. It also replaces legacy framework dependencies and resolves hard-coded version numbers that would otherwise block future patching. The agentic engine handles the complex transformation activity that would previously have consumed months of engineering time per service. The team then checks for any remaining hard-coded version numbers and pushes the transformed code to GitHub.

Phase 3: Deterministic testing and deployment. The transformed code is built and deployed into lower environments, and API gateway routing is updated to point to Amazon ECS. The service is then validated through the same automated regression and performance test packs run during Phase 1. Results are compared against the baseline to confirm that business logic is preserved. Human-in-the-loop code reviews, security and code quality scanning, a service operations review, and cybersecurity approval confirm that every service meets BA’s standards before support handover and go-live.

This separation of concerns is deliberate. Deterministic steps handle everything that should be repeatable and auditable. Agentic AI handles the complex transformation work that would otherwise consume months of engineering time. The result is a repeatable engine that can securely and accurately process hundreds of services far faster than a manual, service-by-service migration.

With AWS Transform custom, British Airways can:

  • Accelerate the modernization of Java services while reducing the manual effort required from engineers.
  • Move services from Amazon EC2 to a more scalable architecture using Amazon ECS on AWS Fargate with Graviton, supported by testing and assurance to confirm that business logic continues to perform as intended.
  • Upgrade outdated software versions and frameworks, supporting a more resilient and maintainable platform.
  • Apply lessons from the work to other engineering activities, including improving unit-test coverage.

Outcome

The benefits go beyond the technology itself. By reducing the manual effort involved in modernization, BA can give engineers more time to focus on resilient technology and better experiences for colleagues and customers.

“Modernising hundreds of code repositories is a significant engineering challenge. By combining agentic and generative AI and automation with human review and assurance, we’re accelerating that work and reducing the manual effort involved. Most importantly, it gives our engineers more time to focus on delivering value to the business and better experiences for our colleagues and customers.”

— Gary Holland, Principal Platform Architect at British Airways

“This is more than a technology upgrade. It is about building stronger, more resilient technology foundations for British Airways so our teams can deliver change more quickly and create better experiences for our customers. The early results are encouraging, and we are now applying what we have learned across the wider platform.”

— Liz Wright, Director of Delivery for BA Digital Customer and Commercial

Get started today

For British Airways, the work demonstrates how modern cloud technology, automation, and responsible use of AI can strengthen the airline’s technology foundations and create more capacity to innovate for customers.

If you’re planning to modernize your own Java applications, explore AWS Transform custom to see how agentic AI and automation, combined with human review, can reduce the manual effort involved.

To hear more about this work, register for session MAM318 at AWS re:Invent 2026.


About the authors

Shane Routley

Shane Routley

Shane is a Senior Customer Solutions Manager at AWS, guiding enterprise customers in the UK and Ireland on their AI and cloud adoption journeys. With two decades of experience in IT transformation and product management, Shane helps customers deliver technology solutions that create business value. He has worked in the technology services, healthcare, and fast-moving consumer goods (FMCG) industries. Shane is based in the UK.

Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan (Venu) is a Principal Specialist Solutions Architect at AWS. He leads generative AI initiatives that focus on Kiro and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation.

Migrate Apache Solr to Amazon OpenSearch Service with the AI-driven Migration Assistant

Post Syndicated from Michael Torio original https://aws.amazon.com/blogs/big-data/migrate-apache-solr-to-amazon-opensearch-service-with-the-ai-driven-migration-assistant/

If you have run Apache Solr for years, you can offload its undifferentiated operational overhead: managing ZooKeeper quorums, patching JVMs, tuning garbage collection, and building custom plugins for features a managed service provides out of the box. Moving to a managed service with native AWS integrations and capabilities like vector search is attractive, but the migration itself is what keeps you on aging infrastructure. Schemas differ between Solr and OpenSearch. Application code is written against the Solr HTTP API, custom analyzers are baked in, and the project balloons into months of engineering work.

A 2024 AWS Big Data Blog post on migrating from Apache Solr to OpenSearch laid out the conceptual differences between the two engines and what to think about at a planning level. However, it left the execution to the reader. In this post, you execute a Solr-to-OpenSearch Serverless migration end to end using the Migration Assistant for Amazon OpenSearch Service from the AWS Solutions Library that runs on Amazon Elastic Kubernetes Service (Amazon EKS). It orchestrates the migration. The Migration Assistant Command Line Interface (CLI) includes a built-in interactive mode that guides you through the assessment and execution in plain language. If you’re only assessing a migration, you can run the AI advisor standalone from your development environment without provisioning infrastructure.

This walkthrough uses Apache Solr 9.6 as the source with a demo catalog of 600,000 synthetic product documents. The same flow applies if you are running Elasticsearch 5.x or later, or a self-managed OpenSearch cluster as your source.

Note: The prompts and responses shown in this post are directional. Because interactive mode uses natural language, your exact prompts and responses might vary by Migration Assistant version and your environment.

By the end of this post, you will have migrated a 600,000-document Apache Solr catalog to Amazon OpenSearch Serverless using the AI-driven agent mode in the Migration Assistant for Amazon OpenSearch Service, from assessment through validated backfill. On the target, you no longer maintain ZooKeeper quorums, JVMs, or custom plugins.

Solution overview

The Migration Assistant for Amazon OpenSearch Service guides you through the various phases of the migration, including deploying the necessary infrastructure components, such as an Amazon EKS cluster. The Migration Assistant guides you through three phases:

  • Assess – Inventory the source schema and query patterns. Check permissions and accessibility. Surface incompatibilities before any data moves.
  • Backfill – Snapshot the source into Amazon Simple Storage Service (Amazon S3), then stream the snapshot into the target using Reindex-from-Snapshot (RFS).
  • Validate – Compare document counts, mappings, sample query results, and replay consistency between source and target.
Migration Assistant architecture on Amazon EKS with RFS workers for backfill and capture proxies for live traffic

Figure 1: Migration Assistant architecture on Amazon EKS, showing the RFS workers for backfill and the capture proxies for live traffic

Prerequisites

Before starting, verify that you have the following:

  • A compatible coding assistant installed and configured. Agent Mode runs inside supported development environments.
  • AWS credentials configured for the target account (AWS IAM Identity Center, temporary credentials, or an AWS Identity and Access Management (IAM) role with sufficient permissions).
  • Account isolation – Use a dedicated non-production account for this walkthrough, or assume a scoped deployment role with short-lived credentials from AWS IAM Identity Center. Point the Migration Assistant at a non-production Solr, Elasticsearch, or OpenSearch source.
  • Deployment permissions – The deployment creates a VPC, a NAT gateway, an Amazon EKS cluster, IAM roles, an Amazon Elastic Container Registry (Amazon ECR) repository, and an Amazon S3 bucket through AWS CloudFormation, so the deploying principal needs permissions to create those resources and to pass roles (iam:PassRole). See the Migration Assistant required-permissions guidance for the exact policy.
  • Workflow pod scope – The migration workflow pods use Amazon EKS Pod Identity to assume a role limited to the snapshot and capture Amazon S3 bucket and the target OpenSearch Serverless collection, rather than broad account access.
  • AWS Command Line Interface (AWS CLI) v2 (latest 2.x release recommended) installed and configured.
    • Verify installation: aws --version.
  • kubectl and Helm installed (the agent uses kubectl to interact with the Amazon EKS-based Migration Assistant infrastructure, and the deployment installs the Migration Assistant as a Helm chart).
    • Confirm both are on your PATH: kubectl version --client && helm version.
  • Network access from your workstation to AWS APIs and, optionally, to the source cluster for assessment.
  • Source cluster details – Endpoint, version, and authentication method for your Solr, Elasticsearch, or OpenSearch cluster.

The tool will prompt you if any of the above aren’t configured.

Install the Migration Assistant CLI

Run the following command in your terminal:

curl -fsSL https://solutions-reference.s3.us-east-1.amazonaws.com/migration-assistant-for-amazon-opensearch-service/3.98.7/install.sh | bash
The install script comes from the official AWS Solutions release channel, the solutions-reference Amazon S3 bucket, and is published by the AWS Solutions release pipeline. For transparency, you can review the source for Migration Assistant for Amazon OpenSearch Service in the aws-solutions/migration-assistant-for-amazon-opensearch repository on GitHub. This post pins version 3.98.7 for repeatable results. Check the Migration Assistant documentation for the current release and substitute the latest version in the install URL.

The one-line command pipes a script straight into bash. The 3.98.7 script runs without sudo. It downloads a single platform binary into ~/.local/bin and runs chmod +x on it, but it doesn’t verify a checksum or signature, and checksums are not currently published for the binaries. The only protection is HTTPS from the AWS-owned Amazon S3 bucket. For a safer install, download the script first, review it, then run it:

curl -fsSL https://solutions-reference.s3.us-east-1.amazonaws.com/migration-assistant-for-amazon-opensearch-service/3.98.7/install.sh -o install.sh
less install.sh # review what the script does before running it
bash install.sh

The installer places the migration-assistant binary on your PATH and prompts you to launch the Migration Assistant by running the following:

migration-assistant

You’re given two options: Manual or Agent Mode. Choose Agent Mode for an AI-guided migration experience.

If you have more than one supported development assistant on your PATH, the CLI detects them and asks which one to use.

Select your preferred option to proceed with the migration.

The interactive mode then prompts you for what you want to accomplish. You can request:

  • An assessment – The agent connects to your source cluster (read-only), analyzes the schema, identifies compatibility gaps, and produces a migration assessment report.
  • A deployment – The agent deploys the Migration Assistant infrastructure (an AWS CloudFormation stack, Amazon EKS cluster, and Helm chart) into your AWS account.
  • A migration – The agent configures and runs the end-to-end migration workflow, including historical data backfill and optional live traffic capture and replay.

Describe your goal in plain language. For example, “Assess my Solr 9.6 cluster. I am evaluating a migration” or “Migrate my Solr 8.11 cluster to OpenSearch Serverless.”

Data handling in agent mode – Agent mode runs inside a third-party coding assistant. To reason about your migration, the agent sends context to that model, including your Solr schema and solrconfig.xml, sample queries, and your source and target endpoints. If you have data-handling rules, review what your coding assistant transmits before you use agent mode.

The agent doesn’t store your credentials and shows each command before it runs. The local ./migration-assistant-workspace/ folder holds migration state, logs, and the assessment report, so treat that folder as sensitive and protect it like other credential-adjacent artifacts.

Assessing a migration

The first step is to run a full assessment of the source cluster. In this phase, nothing changes on the source. The agent takes inventory and reports back on what is missing or incompatible. Tell Migration Assistant to perform the assessment:

“Run a migration assessment of my Solr collection. The source is Solr 9.6.1 in SolrCloud mode at https://solr.example.internal:8983/solr, collection name products, 600,000 docs.”

You provide the source location directly in the prompt. Give the agent the Solr endpoint (for SolrCloud, any node’s base URL, or your ZooKeeper connection string) along with the collection name and authentication method. If you leave out the endpoint, the agent asks for it before it connects, because the assessment phase needs to reach the source to read the schema and solrconfig.xml.

The agent connects to Solr in read-only mode, takes inventory of the collection, and prints a structured report covering:

  • Source – Endpoint, version, mode, collection size, authentication.
  • Schema/field types – Dield-type classes in use, language analyzers declared.
  • solrconfig.xml – Request handlers, search components, update processors.
  • Custom plugins – Custom Java plugins detected, with recommended OpenSearch equivalents.
  • Networking – Verifies Migration Assistant can reach the source and that the S3 snapshot repository is loaded in Solr.

The following screenshot shows the bottom of the assessment report, which details overall readiness based on what the agent found after examining source and target configurations.

Overall readiness section of the assessment report with source checks green and custom plugin remediation yellow

Figure 2: Overall readiness section of the assessment report, where source-side checks pass green and custom plugin remediation is yellow

Field types, document backfill (RFS), live replay transforms, and sample query coverage all pass green. Custom plugin remediation is listed as yellow because the assessment detected three custom Java plugins in the solrconfig.xml that don’t translate automatically and require refactoring by your team. The target-side checks show N/A because a target has not been configured yet. After you add a target endpoint, re-running the assessment populates those rows.

Deploying the Migration Assistant infrastructure

Before moving on, save the assessment report so the findings stay available as a reference during the migration. The agent stores the report in your workspace and can recall specific findings later when you configure the workflow.

A green assessment report indicates that migration is possible and does not move the data. Migration Assistant will be used to migrate the data and build necessary configurations. The Migration Assistant needs infrastructure deployed in your account before it can copy data from Solr to Amazon OpenSearch Serverless. Ask the agent to deploy that infrastructure:

“Deploy the Migration Assistant infrastructure in us-west-2”

When you start the deployment, the agent asks for a stage name. The stage is a label you choose, not a value from a fixed list. The agent uses it as the Kubernetes namespace for the pods, the Helm release name, and the suffix on the CloudFormation stack (MigrationAssistant-<stage>). Accept the default ma, or pick something more descriptive like dev, prod, or solr-migration.

Under the hood, the agent deploys a CloudFormation stack that provisions:

Total time to install the Migration Assistant is approximately 10–15 minutes. The agent monitors pod state and reports when the infrastructure is ready.

Backfilling Solr data

After addressing data-access gaps and confirming the assessment is green, you instruct the agent to run the backfill and give it the target endpoint:

“Run the backfill into my OpenSearch Serverless collection at”

You specify the target OpenSearch Serverless endpoint here, in the backfill request. If you leave it out, the agent asks for the collection endpoint and confirms the Region and SigV4 authentication before it builds the workflow. You review that configuration next.

Before starting the backfill, the agent generates a workflow configuration that captures the migration configuration in a single JSON document: source and target endpoints, authentication, snapshot location, and RFS worker settings. The agent prints the configuration for you to review and approve, so nothing runs until you confirm.

Workflow configuration JSON showing source cluster, S3 snapshot repository, target endpoint, and RFS worker settings

Figure 3: Workflow configuration JSON, part 1, showing the source cluster, S3 snapshot repository, target OpenSearch Serverless endpoint, and RFS worker settings

The JSON defines the source Solr cluster endpoint and version, the S3 bucket where the Solr snapshot is stored, and the target OpenSearch Serverless collection endpoint. Because the Migration Assistant uses Reindex-from-Snapshot, you point the s3RepoPathUri at the S3 bucket provided for storing the snapshot. The target can be either an Amazon OpenSearch Service domain or an OpenSearch Serverless collection.

This Solr cluster uses basic authentication. You can create a Kubernetes secret in the Migration Assistant namespace after deployment and reference that secret by name in the workflow configuration. You can ask the agent to create the secret, or run the command yourself:

kubectl create secret generic solr-basic-auth --namespace ma --from-literal=username='YOUR_SOLR_USERNAME' --from-literal=password='YOUR_SOLR_PASSWORD'

The preceding command passes the password with --from-literal, which leaves it in your shell history and the process list. For anything beyond a quick test, read the password without echoing it and pass it through a restricted-permission file that you delete afterward:

read -s SOLR_PASSWORD # prompt without echoing to the terminal
umask 077 # restrict permissions on files you create
printf '%s' "$SOLR_PASSWORD" > solr-password.txt
kubectl create secret generic solr-basic-auth --namespace ma \
--from-literal=username='YOUR_SOLR_USERNAME' \
--from-file=password=solr-password.txt
rm -f solr-password.txt # remove the file once the secret exists
unset SOLR_PASSWORD

As an alternative, store the Solr credential in AWS Secrets Manager and resolve it at deploy time instead of placing it in a shell command. Either approach keeps the password out of your shell history and the process list.

Use the stage name you chose during deployment as the namespace (ma is the default), and reference the secret name (solr-basic-auth) in the workflow configuration so the agent can authenticate the source.

Grant the target collection a data access policy

For an OpenSearch Serverless target, the Migration Assistant workflow pod role must be allowed to write to the target collection. Grant that access through a data access policy scoped to the target collection and index, and confirm the collection is reachable through its network policy. Scope the policy to the specific collection and index rather than *:

[
  {
    "Rules": [
      {
        "ResourceType": "index",
        "Resource": ["index/solr-migration/products"],
        "Permission": [
          "aoss:CreateIndex",
          "aoss:DescribeIndex",
          "aoss:WriteDocument",
          "aoss:ReadDocument"
        ]
      },
      {
        "ResourceType": "collection",
        "Resource": ["collection/solr-migration"],
        "Permission": ["aoss:DescribeCollectionItems"]
      }
    ],
    "Principal": [
      "arn:aws:iam::<account-id>:role/<migration-assistant-workflow-role>"
    ]
  }
]

Secure the snapshot and capture bucket

Reindex-from-Snapshot reads a Solr snapshot from Amazon S3, so the Solr nodes need write access to the snapshot bucket to create that snapshot. Attach an IAM policy scoped to only the snapshot bucket and prefix rather than a broad Amazon S3 grant:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["s3:PutObject", "s3:GetObject", "s3:ListBucket"],
      "Resource": [
        "arn:aws:s3:::migration-assistant-snapshots",
        "arn:aws:s3:::migration-assistant-snapshots/solr-migration/*"
      ]
    }
  ]
}

Turn on Amazon S3 Block Public Access for the bucket and turn on encryption at rest, either with Amazon S3 managed keys (SSE-S3) or AWS Key Management Service (AWS KMS) keys (SSE-KMS).

The same bucket also holds captured traffic tuples, which can contain real user queries and personally identifiable information (PII). Keep that data only as long as you need it for cutover validation, and delete it after cutover.

To capture live traffic updates as part of the migration, the configuration also provides a replayer. The replayer captures live traffic at the source through a proxy and mirrors it into the target. The Migration Assistant uses SolrToOpenSearchTransformProvider to read the Solr schema and config files to translate queries in real time.

Workflow configuration JSON showing the capture proxy and replayer with the SolrToOpenSearchTransformProvider

Figure 4: Workflow configuration JSON, part 2, showing the capture proxy and the replayer with the SolrToOpenSearchTransformProvider for live query translation

After you approve the workflow, the Migration Assistant control plane starts spinning up resources. Within about a minute, the migration-console pod reports that the metadata phase ran successfully and can create an index in the target collection.

If the tool can’t migrate a specific item, the tool logs the issue and continues where safe. Some issues are fatal, such as an index that already exists on the target or a field type the transformer can’t convert. These cause the phase to exit non-zero so you can fix the problem and rerun. The Migration Assistant skips already migrated items on retry.

Some categories are out of scope for the metadata phase and require separate planning: security configuration, ISM and ILM policies, ingest pipelines, Dashboards saved objects, data streams, and cluster level settings.

Metadata evaluation output showing zero issues and one products index to create on the target

Figure 5: Metadata evaluation output showing zero issues detected and one index, products, to create on the target

Open a second terminal to monitor the migration. Launch migration-assistant and select [1] Manual when asked how you want to drive the migration, which opens the migration-console. With the migration-console open, run the following command to confirm the target index was created with zero documents:

console clusters cat-indices --cluster target
cat-indices output showing the products index created with zero documents

Figure 6: cat-indices output showing the products index created with 0 documents, confirming the metadata migration succeeded

The agent confirms the mappings are correct, including the dynamic templates for Solr’s dynamic-field patterns, and asks for approval to start RFS. You approve, and RFS workers spin up on EKS. To watch documents flow into the target in real time, run a watch loop against the same cat-indices command in the migration-console:

watch -n 3 'console clusters cat-indices --cluster target'

The console command inside the migration console pod exposes utilities for driving and inspecting a migration outside the workflow CLI. In addition to clusters cat-indices, you have clusters connection-check, clusters curl, and snapshot, among others. Run console --help inside the pod to view the full list.

The document count climbs steadily as the three RFS worker pods stream the snapshot into the new index. The workflow configuration you approved earlier set three RFS worker replicas, so three pods run the backfill in parallel here. You can raise or lower that replica count to control how much the backfill parallelizes. The following screenshot shows the migration mid-flight at roughly the halfway point.

cat-indices output showing 304,441 documents migrated into the products index mid-migration

Figure 7: Mid-flight progress showing 304,441 documents migrated into the products index

After the backfill completes, you can confirm the final document count directly from OpenSearch Dashboards Dev Tools. The following query against the migrated collection returns the exact count:

OpenSearch Dashboards Dev Tools showing a document count query returning 600,000 documents

*Figure 8: OpenSearch Dashboards Dev Tools, where GET products/_count returns 600,000 documents, confirming the backfill is complete*

Validation and testing

With the backfill finished, ask the agent to run a validation check. The agent runs four checks and prints results:

Validation results showing doc count, query, mapping, and facet parity matching and end-to-end migration success

Figure 9: Validation results, where doc count, sample query, mapping, and facet parity all match, spellcheck shape differs, and the end-to-end migration succeeds

Four lines worth reading carefully:

  • Doc count parity (600k): MATCH – Solr has 600,000 documents and the OpenSearch Serverless collection has 600,000.
  • Sample query parity (9/9 result-shape tests): MATCH – The same queries that translated cleanly in the assessment returned matching results against the target.
  • Mapping spot-check (11 business fields): All correct types – The most-used product fields (title, brand, category, price, in_stock, rating, and others) ended up with the data types that their queries depend on.
  • Facet aggregation parity: MATCH with shard_size=200 – Facet results match when the shard_size parameter is set explicitly (the default produces approximate counts).

The one yellow line is Spellcheck shape: differs (known, app rewrite), which the assessment had already flagged. Application code that consumes spellcheck responses will need to be updated to handle the OpenSearch response format.

Running a query against your migrated data

Running a real query against the migrated collection confirms that translated query domain-specific language (DSL) works on the target. You don’t need to translate queries by hand.

In agent mode, give the agent your Solr query and ask for the OpenSearch equivalent, for example, “Translate my eDisMax lamp query to OpenSearch Query DSL.”

The agent returns the DSL for you to paste into OpenSearch Dashboards Dev Tools. This is interactive help for individual queries. The backfill workflow itself does not translate or replay Solr queries, so you still rewrite your application’s query layer.

To follow along, open Dev Tools and run one of the translated queries from the assessment: a multi-field text search with a field boost, a category filter, a price range, and a sort. The Solr version of that query, in its native URL form:

GET /solr/products/select?q=lamp&defType=edismax&qf=title^3 description&fq=category:electronics&fq=price:[0 TO 1000]&sort=rating desc&rows=10

The equivalent OpenSearch Query DSL:

GET products/_search
{
  "size": 10,
  "query": {
    "bool": {
      "must": [
        {
          "multi_match": {
            "query": "lamp",
            "fields": ["title^3", "description"],
            "type": "best_fields"
          }
        }
      ],
      "filter": [
        { "term": { "category": "electronics" } },
        { "range": { "price": { "gte": 0, "lte": 1000 } } }
      ]
    }
  },
  "sort": [
    { "rating": "desc" }
  ]
}

The translation is mechanical: Solr’s q=lamp becomes a multi_match clause, fq filters become bool.filter entries, and sort keeps the same shape. The following screenshot shows both queries side by side in Dev Tools, along with the OpenSearch response.

OpenSearch Dashboards Dev Tools showing the translated query and response with 2,356 matching documents

Figure 10: OpenSearch Dashboards Dev Tools showing the translated OpenSearch query and its response, returning 2,356 matching documents

The response shows 2,356 matching documents returned in 170 milliseconds, with the top hits sorted by rating, all queryable through the new OpenSearch Serverless endpoint.

Updating your application code

The Migration Assistant moves your data and schema, and it can also mirror live Solr traffic to the target during migration. The capture proxy records requests to your source, and the replayer sends them to OpenSearch using the SolrToOpenSearchTransformProvider you configured earlier. It reads your Solr schema and solrconfig.xml to translate queries in a field-type-aware way. That translation covers common Solr query and update patterns. It returns an error on features it doesn’t support rather than translating them incorrectly, so check the Migration Assistant documentation for the current list of supported behavior. This path is built for migration and cutover validation, not as a permanent production query layer. Because Solr and OpenSearch differ in query syntax, request handlers, and response shape, you still rewrite your application’s query layer for production. Two AI-driven paths are available:

AWS Transform is a collaborative IT transformation workbench that accelerates cloud migration, application modernization, and technical debt reduction. AWS Transform delivers high-quality, repeatable transformations without requiring specialized automation expertise. You can also handle the refactoring using available development tools your team uses for application development to help rewrite the relevant Solr client calls to use the OpenSearch client.

An AI coding assistant can also handle the refactoring. Any AI coding assistant that your team uses for application development can read your repository and rewrite the relevant Solr client calls to use the OpenSearch client. For better results, AWS provides integration tools that help. These tools reference AWS documentation and include Solr to Amazon OpenSearch Service capabilities that the Migration Assistant uses. This approach is less structured than AWS Transform but can be done with your existing development tools.

As you plan the query rewrite: devise a strategy for each of the following areas:

  • Query parser differences – Solr’s eDisMax qf/pf/bf/bq/mm don’t map 1:1 to OpenSearch. multi_match with type: best_fields or most_fields is the closest analogue, but boost math (bf) and phrase-field boosting (pf) require rewrites.
  • Request handler configs – Solr solrconfig.xml request handlers (with defaults, appends, invariants) become search templates or application logic on OpenSearch.
  • Response format – Solr’s response.docs compared to OpenSearch’s hits.hits.
  • Function queries and score modifications – Solr’s _val_, bf, and function query syntax must be rewritten as function_score or script_score. Semantics are close but rarely identical, and BM25 compared to Solr’s TF-IDF (or BM25 in newer Solr) produces different absolute scores.
  • Faceting – Solr facet.field, facet.range, and facet.pivot become OpenSearch aggregations.
  • Highlighting, fl field selection, and cursorMark pagination – All have OpenSearch equivalents with different names and semantics.

Bonus: Improve search relevance with Automatic Semantic Enrichment

After your data lands in an OpenSearch Serverless collection, you have access to capabilities that weren’t available on Solr such as vector based search and semantic enrichment. One option is Automatic Semantic Enrichment. Automatic Semantic Enrichment uses a pre-trained sparse encoder (opensearch-neural-sparse-v2) to expand each document with weighted co-occurring terms at indexing time. It then matches incoming queries against the expanded representation. You get relevance improvements without hosting a model or running inference at query time.

Consider a query like “durable rain jacket” against a product catalog. A keyword-only search returns documents that contain those literal words. With Automatic Semantic Enrichment activated, the same query also surfaces related items like waterproof shells, hardshells, and weatherproof coats, without anyone writing or maintaining synonym files. Automatic Semantic Enrichment is configured at index creation time and can’t be activated by changing the mapping afterward. After activation, sparse vectors are generated automatically for every ingested document. The AI assistant will help you set up a semantically enriched field as part of the migration.

Cost

The Migration Assistant infrastructure costs approximately $0.40–0.70 per hour while running. The target OpenSearch Serverless collection has a separate baseline cost. OpenSearch Serverless can scale compute to zero when idle, so you pay only for storage when the collection is not handling requests, and it provisions faster than previous generations.

Clean up

When you finish testing, remove the resources you created so you don’t keep paying for them:

  • Delete the AWS CloudFormation stack MigrationAssistant-<stage>, which removes the VPC, NAT gateway, Amazon EKS cluster, Amazon ECR repository, and IAM roles it created.
  • Empty and delete the Amazon S3 bucket that holds the snapshot and the captured traffic tuples.
  • Delete the Kubernetes secret solr-basic-auth and remove the container images from the Amazon ECR repository.
  • Remove any temporary access you granted on the Solr source, and revoke the data access policy entry you added to the target OpenSearch Serverless collection.

Conclusion

The Migration Assistant reduces the manual engineering effort required to move from Apache Solr to Amazon OpenSearch Serverless. The Migration Assistant handles orchestration and guides you through assessment, backfill, and validation, while development tools can help reduce the effort needed to rewrite application code.

Try the Migration Assistant for Amazon OpenSearch Service in your own AWS account. Point it at a non-production Solr, Elasticsearch, or self-managed OpenSearch cluster and describe your goal in language, for example, “Deploy Migration Assistant in us-west-2 so I can start testing” or “Run the historical data migration for my Elasticsearch 7.10 cluster.” Run an assessment and take a workload through backfill and validation to see how the Assistant handles the process for you. As you use the Migration Assistant on your own projects, tell us what worked and where you encountered challenges, so we can keep improving the assessment, translation, and validation experience.


About the authors

Michael Torio

Michael Torio

Michael is an OpenSearch Specialist Solutions Architect based in Mountain View, CA. He works with customers across every stage of their data analytics journey, helping them design, scale, and operate OpenSearch in production.

Jon Handler

Jon Handler

Jon is a Senior Principal Solutions Architect at AWS based in Palo Alto, CA. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have vector, search, and log analytics workloads that they want to move to the AWS Cloud. Prior to joining AWS, Jon’s career as a software developer included 4 years of coding a large-scale, ecommerce search engine. Jon holds a Bachelor’s of the Arts from the University of Pennsylvania, and a Master’s of Science and a PhD in Computer Science and Artificial Intelligence from Northwestern University.

Analyze Anthropic usage, spend, and access with AWS Glue, Amazon S3 Tables, and AWS Quick

Post Syndicated from Daniyal Alam original https://aws.amazon.com/blogs/big-data/analyze-anthropic-usage-spend-and-access-with-aws-glue-amazon-s3-tables-and-aws-quick/

Finance teams want to allocate AI spend to the business units that use it. Engineering leaders want to know what that spend delivers. Security teams want to know who owns each API key and whether any belong to former employees. Anthropic gives administrators detailed visibility into usage and cost through Claude Code usage analytics and the Anthropic Admin API. Many enterprises want to take the next step and analyze that data alongside the business data they already manage in AWS. Until now that has meant building and maintaining a custom integration with the Admin API.

AWS Glue now offers a native connector for Anthropic. AWS Glue is a serverless data integration service that helps you discover, prepare, move, and integrate data from multiple sources for analytics, artificial intelligence and machine learning (AI/ML), and application development. The connector for Anthropic is one of 100 new native connectors that AWS Glue added for popular software as a service (SaaS) applications. It works like other AWS Glue connectors and requires no custom code. You store an Anthropic API key in AWS Secrets Manager and create an AWS Glue connection that references it. The connector handles the API calls and schema mapping for you so your team can focus on analyzing the data instead of maintaining the integration.

The connector makes AI usage another domain in your data lakehouse. With Amazon S3 Tables, fully managed Apache Iceberg tables in Amazon Simple Storage Service (Amazon S3), you can store your transformed Anthropic and business data in an open and interoperable format that AWS analytics services can read natively and other Iceberg engines can query.

In this post, we follow the fictional retailer AnyCompany Retail as it brings Anthropic data into Amazon S3 Tables and joins it with its own business data using AWS Glue materialized views stored as Apache Iceberg tables. The team uses Amazon Athena to query the data with SQL and answer leadership’s three questions about spend, value, and API key ownership. It then publishes the results to an AWS Quick dashboard that leadership reviews every week.

Solution overview

The following diagram shows the solution architecture.

Solution architecture showing AWS Glue reading Anthropic data through the connector, writing Apache Iceberg tables to Amazon S3 Tables, and Amazon Athena and AWS Quick querying the results

Figure 1: Solution architecture for analyzing Anthropic usage data with AWS Glue, Amazon S3 Tables, Amazon Athena, and AWS Quick

The workflow consists of the following steps:

  1. You store your Anthropic API keys in AWS Secrets Manager, where the AWS Glue connection references them.
  2. An AWS Glue extract, transform, and load (ETL) job uses the Glue connector for Anthropic to read entities such as usage and cost reports, users, and workspaces.
  3. The job transforms the data into fact and dimension tables like daily usage, daily cost, and writes them to Amazon S3 Tables as Apache Iceberg tables.
  4. The job joins the Anthropic data with business data that you own like workspace-to-business-unit mapping, outcome metrics, and an employee directory. In our example, this data is stored in Amazon S3.
  5. Amazon Athena queries the tables to answer the spend, value, and access questions, and AWS Quick presents the results through natural language prompting or dashboards.

Supported entities

Anthropic uses two kinds of API keys, and each provides access to different sets of data. An Admin API key reads organization-level data. A workspace API key reads data inside a single workspace. You create one AWS Glue connection for each key.

Entity API key Description
users Admin Organization members with their email, name, and role
invites Admin Pending and accepted organization invites
workspaces Admin Workspaces in the organization, including the default and archived workspaces
workspace_members Admin Members of each workspace with their workspace role
api_keys Admin API keys with status, scope, workspace, and creator
usage_report Admin Token usage per time bucket, optionally grouped by workspace, API key, model, and more
cost_report Admin Cost per daily bucket, optionally grouped by workspace and cost description
models Workspace Claude models available to the workspace
message_batches Workspace Message Batches API jobs with status and request counts
files Workspace Files uploaded to the workspace

Example scenario

The retailer uses Claude across five business units, each with its own Anthropic workspace: Customer Service, Engineering, Document Processing, Marketing, and Data Science. Every week, leadership reviews AI spend across the business units and asks three questions:

  • Which business units are driving AI spend?
  • Is the spend paying off, for example in cost per resolved customer case?
  • Are any active API keys owned by employees who have left the company?

Throughout this post, the Anthropic data comes from a demo organization. The reference datasets (business-unit mapping, support outcomes, and employee directory) are illustrative samples.

Prerequisites

To follow along, you need the following:

  • An Anthropic organization (Admin API features aren’t available for individual accounts).
  • An Anthropic Admin API key, created by an organization admin.
  • A workspace API key for each workspace you want to analyze.
  • An AWS account with AWS Identity and Access Management (IAM) permissions to use AWS Glue, Amazon Athena, Amazon S3, Amazon S3 Tables, AWS Secrets Manager, and AWS Quick.
  • An IAM role for AWS Glue with access to the secrets, your S3 bucket, and your S3 table bucket (see Part 2).
  • An S3 bucket for job scripts and reference data.

Part 1: Set up the AWS Glue connector for Anthropic

In this part, you store your Anthropic API keys in AWS Secrets Manager and create the AWS Glue connections that read your organization’s data.

Store your Anthropic API keys

Store each API key in AWS Secrets Manager as a secret with the key apiKey:

{ "apiKey": "<your-anthropic-api-key>" }

Create one secret for the Admin API key and one for each workspace API key you plan to use.

  1. Open AWS Secrets Manager.
  2. Choose Store a new secret and enter your API key.

    AWS Secrets Manager Store a new secret page with the Anthropic API key entered

    Figure 2: Storing an Anthropic API key in AWS Secrets Manager

  3. Choose Next and name your new secret.
  4. Optionally, configure automatic rotation.
  5. Afterwards, choose Next and then Store.

Create the connections

  1. On the AWS Glue console, choose Data connections, then Create connection.
  2. For Data source, choose Anthropic.

    AWS Glue Create connection page with Anthropic chosen as the data source

    Figure 3: Choosing Anthropic as the data source in AWS Glue

  3. For Authentication, choose the secret that contains your Admin API key.

    AWS Glue connection authentication step with the Admin API key secret selected

    Figure 4: Selecting the secret that holds the Admin API key

  4. Name the connection, for example anthropic-admin, and create it.
  5. Repeat the steps with a workspace API key to create a second connection, for example anthropic-workspace.

After you create a connection, choose Test connection to validate the API key. Both Admin and workspace API keys can be validated.

AWS Glue connection detail page showing a successful Test connection result

Figure 5: Validating an Anthropic connection with Test connection

Explore and preview data

In the AWS Glue console, you can browse the entities that each connection exposes and preview records and the schema for all the data available through the AWS Glue connector for Anthropic. The following screenshot showcases synthetic data.

AWS Glue console previewing Anthropic entity records and schema for a connection

Figure 6: Previewing Anthropic entities and schema in the AWS Glue console

Part 2: Build an AI usage lakehouse with Amazon S3 Tables and AWS Glue materialized views

In this part, you turn the Anthropic data from Part 1 into answers to leadership’s three questions. An AWS Glue ETL job reads Anthropic data through the connector, combines it with your business data, and writes Apache Iceberg tables to Amazon S3 Tables. A second AWS Glue job maintains AWS Glue materialized views in the AWS Glue Data Catalog, one for each question, and you query the views with Amazon Athena.

The table bucket organizes the data in four namespaces:

Namespace Contents Written by
raw Anthropic entities, as the connector returns them ETL job
reference Business data that you own, loaded from CSV files in Amazon S3 ETL job
curated Daily fact tables and dimension tables, built from the raw data ETL job
mart Materialized views, one for each business question Materialized view job

To build the pipeline, you complete the following steps.

Create the table bucket and namespaces

Create a table bucket, and then create one namespace for each layer:

aws s3tables create-table-bucket --name amzn-s3-demo-table-bucket

for ns in raw curated reference mart; do
  aws s3tables create-namespace \
    --table-bucket-arn arn:aws:s3tables:<region>:<account-id>:bucket/amzn-s3-demo-table-bucket --namespace "$ns"
done

On the Amazon S3 console, choose Table buckets and enable Integration with AWS analytics services. The integration adds your table buckets to the AWS Glue Data Catalog under the s3tablescatalog catalog, so AWS Glue and Athena can address this bucket as s3tablescatalog/amzn-s3-demo-table-bucket. This walkthrough uses IAM access control for the integration.

Amazon S3 Table buckets page with Integration with AWS analytics services turned on

Figure 7: Turning on AWS analytics integration for the table bucket

Upload your business data to Amazon S3

Anthropic data shows what each workspace and API key spends. It doesn’t show which business unit owns a workspace, what the spend produced, or whether the creator of a key still works at the company. That context lives in your own systems, so you create these datasets from your organization’s data. The datasets you need depend on the questions you want to answer. This post uses the following three sample datasets:

Dataset Columns Example row
workspace_business_unit workspace_name, business_unit Customer Service, Customer Service
support_outcomes_daily outcome_date, business_unit, conversations, completed_resolutions, qa_score_pct 2026-10-30, Customer Service, 1216, 990, 96
hr_directory email, employment_status (active or departed) [email protected], departed

Save each dataset as a CSV file with a header row. In your S3 bucket, upload each file to its own folder under a common prefix, and name each folder after its dataset:

s3://<bucket-name>/<prefix>/workspace_business_unit/workspace_business_unit.csv
s3://<bucket-name>/<prefix>/support_outcomes_daily/support_outcomes_daily.csv
s3://<bucket-name>/<prefix>/hr_directory/hr_directory.csv

The ETL job reads each folder and loads it into a table with the same name in the reference namespace.

Note: If your datasets or columns differ, update REFERENCE_DATASETS in the ETL script and the materialized view definitions to match.

Grant the AWS Glue role access

Both jobs use the IAM role for AWS Glue from the prerequisites. Make sure that the role can do the following:

  • Read the Secrets Manager secrets that store your Anthropic API keys.
  • Read the job scripts and reference data in your S3 bucket.
  • Read and write the table bucket and its tables in the AWS Glue Data Catalog, as described in Amazon S3 Tables integration with AWS analytics services.
  • Pass itself to AWS Glue. Grant iam:PassRole on the role’s own ARN for glue.amazonaws.com, because AWS Glue stores the role with each materialized view and uses it to refresh the view.

Review the ETL script

The ETL job runs the script anthropic_usage_etl.py. Download anthropic_usage_etl.py and save it on your computer. You upload it when you create the AWS Glue job in a later step.

On each run, the script does the following:

  • Reads the cost report, usage report, users, workspaces, and API keys through the Admin connection, and message batches and files through any workspace connections that you list. It writes this data unchanged to the raw namespace.
  • Reads your business data from the Amazon S3 location in the --reference_data_path job parameter and writes it to the reference namespace.
  • Flattens the usage and cost reports into daily fact tables, converts cost from cents to US dollars, and builds tables of API keys, users, and workspaces in the curated namespace.
  • Creates any table that doesn’t exist yet and adds columns when the source data gains new fields, so you don’t need to create tables in advance.

The following snippets show three important parts of the script: how it reads data through the connector, how it builds the curated tables, and how it loads new data incrementally.

Read Anthropic data through the connector

The connector reads data directly into Apache Spark DataFrames through CatalogConnectionHelper, a helper library included with AWS Glue. You pass the connection type, the AWS Glue connection name, and the read options. For every read option and the fields that support filter pushdown, see Anthropic connection options. The following example reads the cost report from October 1, grouped by workspace and cost description:

from connectivity.adapter import CatalogConnectionHelper

connector = CatalogConnectionHelper(spark)

def read_entity(entity, connection, filter_predicate=None):
    """Read one Anthropic entity through the AWS Glue connection into a Spark DataFrame."""
    options = {"ENTITY_NAME": entity}
    if filter_predicate:
        options["FILTER_PREDICATE"] = filter_predicate
    return connector.read("anthropic", connection, options) # connection type, connection name, options

def read_report(entity, starting_at, group_by):
    """Read a usage or cost report from starting_at, broken down by the group_by dimensions."""
    conditions = [f"starting_at = '{starting_at}'"] + [f"group_by = '{field}'" for field in group_by]
    report = read_entity(entity, "anthropic-admin", " AND ".join(conditions))
    return report.select("starting_at", "ending_at", "results")

cost_report = read_report("cost_report", "2026-10-01T00:00:00Z", group_by=["workspace_id", "description"])

read_report builds the filter predicate from the start date and group_by dimensions, and keeps the report columns that the job uses. The result is a Spark DataFrame, so you can use it with standard Spark transformations without converting it. The job reads cost_report and usage_report with read_report and users, workspaces, and api_keys with read_entity.

Workspace entities, such as message_batches and files, need a workspace API key, so the job reads them through each workspace connection that you list in the --workspace_connections job parameter. The job writes everything that it reads, unchanged, to the raw namespace.

Build the curated tables

The connector returns the cost report as one record per day. That record holds all of the day’s cost lines in a single field, results, as a JSON array. To analyze individual cost lines, the job parses results with a schema for the cost line fields (COST_LINE_SCHEMA) and expands the array, so that each cost line becomes its own row. Anthropic reports cost amounts in cents, so the job converts them to US dollars. Anthropic also reports activity in the Default workspace with an empty workspace_id, so the job fills in the Default workspace ID:

def build_fact_cost_daily(cost_report, default_workspace_id):
    """One row per day, workspace, and cost line, with the amount converted from cents to US dollars."""
    return (
        cost_report
        .withColumn("line", F.explode(F.from_json("results", COST_LINE_SCHEMA)))
        .select(
            F.to_date("starting_at").alias("cost_date"),
            # Anthropic reports Default workspace activity with an empty workspace_id
            F.coalesce("line.workspace_id", F.lit(default_workspace_id)).alias("workspace_id"),
            "line.description",
            "line.model",
            "line.cost_type",
            "line.token_type",
            "line.currency",
            (F.col("line.amount").cast("decimal(20,8)") / 100).alias("amount_usd"),
        )
        .groupBy(*COST_KEYS)
        .agg(F.sum("amount_usd").alias("amount_usd"))
    )

The job also parses nested fields such as the API key creator, scope, and principal. It writes the following tables to the curated namespace:

Table Contents
fact_usage_daily Token usage per day, workspace, API key, and model
fact_cost_daily Cost in US dollars per day, workspace, and cost line
dim_api_key API keys with status, workspace, creator, and key type (linked to a user, service account, or legacy)
dim_user, dim_workspace Organization members and workspaces

Load new data incrementally

The first run loads all data from the date in the --start_date job parameter. Later runs re-read only the last three days, because daily buckets close after midnight UTC and recent days can still change. The job merges those days into the fact tables, so a rerun updates rows instead of duplicating them:

MERGE INTO s3tables.curated.fact_cost_daily t
USING updates s -- the re-read days
ON t.cost_date <=> s.cost_date AND t.workspace_id <=> s.workspace_id
AND t.description <=> s.description AND t.model <=> s.model
AND t.cost_type <=> s.cost_type AND t.token_type <=> s.token_type
AND t.currency <=> s.currency
WHEN MATCHED THEN UPDATE SET *
WHEN NOT MATCHED THEN INSERT *;

The dimension and reference tables are small, so the job replaces them on every run.

Review the materialized view script

The materialized view job runs the script anthropic_usage_mvs.py. Download anthropic_usage_mvs.py and save it on your computer.

The curated tables hold clean usage, cost, and access data, but each leadership question needs joins across several of them and your business data. Instead of repeating those joins in every query and dashboard, the script saves each answer as a materialized view in the mart namespace. A materialized view stores the result of a query as an Iceberg table. When its base tables change, a refresh updates the view, incrementally where possible, instead of recomputing the whole query. Athena and AWS Quick then read the precomputed results, so everyone works from the same numbers.

On each run, the script creates any view that doesn’t exist yet and refreshes the rest. It maintains one view for each leadership question:

View Built from Answers
weekly_spend_by_business_unit fact_cost_daily, dim_workspace, workspace_business_unit Which business units are driving AI spend?
unit_cost fact_cost_daily, dim_workspace, workspace_business_unit, support_outcomes_daily Is the spend paying off?
access_review dim_api_key, dim_user, dim_workspace, fact_usage_daily, hr_directory Are any active API keys owned by employees who have left?

Add your own views

The script is extensible. Each view is one entry in the VIEWS dictionary: the key is the view name, and the value is the view’s SQL query. To answer a new question, add an entry. For example, the following entry adds a view of daily token usage by workspace and model:

VIEWS = {
    # ... the three views in the preceding table ...
    # Which models consume the most tokens in each workspace?
    "tokens_by_model": f"""
        SELECT u.usage_date,
            w.name AS workspace,
            u.model,
            sum(u.uncached_input_tokens) AS uncached_input_tokens,
            sum(u.cache_read_input_tokens) AS cache_read_input_tokens,
            sum(u.output_tokens) AS output_tokens
        FROM {CURATED}.fact_usage_daily u
        LEFT JOIN {CURATED}.dim_workspace w ON w.workspace_id = u.workspace_id
        GROUP BY 1, 2, 3
    """,
}

The next run of the job creates the view, and later runs refresh it. To change the definition of an existing view, set the optional --recreate job parameter to the view name, for example tokens_by_model, for one run. The job drops the view and creates it again with the new definition.

Follow two rules when you write a view definition:

  • Make definitions deterministic. Functions such as current_date() aren’t allowed, so calculate those values at query time.
  • Use inline subqueries instead of a WITH clause. In our testing, views that used a WITH clause could be created but failed to refresh.

Create the AWS Glue jobs

Create one AWS Glue job for each script. Both jobs connect to the table bucket with the same job parameter, so prepare its value first.

Prepare the table bucket configuration

The scripts read and write the table bucket through an Apache Spark catalog named s3tables. You configure the catalog with one job parameter, --conf. Copy the following value as a single line, and replace <account-id>, <region>, and amzn-s3-demo-table-bucket with your own values:

spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions --conf spark.sql.catalog.s3tables=org.apache.iceberg.spark.SparkCatalog --conf spark.sql.catalog.s3tables.type=glue --conf spark.sql.catalog.s3tables.glue.id=<account-id>:s3tablescatalog/amzn-s3-demo-table-bucket --conf spark.sql.catalog.s3tables.glue.account-id=<account-id> --conf spark.sql.catalog.s3tables.glue.region=<region> --conf spark.sql.catalog.s3tables.client.region=<region> --conf spark.sql.catalog.s3tables.warehouse=s3://amzn-s3-demo-table-bucket/warehouse/

The value contains several Spark settings. AWS Glue accepts only one --conf parameter, so the settings are separated by --conf inside the value. With this configuration, the scripts refer to tables as s3tables.<namespace>.<table>, for example s3tables.curated.fact_cost_daily. For details about these settings, see Running ETL jobs on Amazon S3 tables with AWS Glue.

Create the ETL job

  1. On the AWS Glue console, choose ETL jobs, and then choose Script editor.
  2. For Engine, choose Spark. Choose Upload script, select anthropic_usage_etl.py, and choose Create script.
  3. On the Job details tab, for Name, enter anthropic-usage-etl. For IAM Role, choose the role from the prerequisites. For Glue version, choose Glue 6.0.
  4. Expand Advanced properties. Under Connections, choose the Admin connection and each workspace connection that you created in Part 1.
  5. Under Job parameters, choose Add new parameter and add each of the following keys and values:
Key Value Purpose
--datalake-formats iceberg Adds Apache Iceberg support to the job
--conf The value that you prepared Connects the job to the table bucket
--admin_connection anthropic-admin Name of the Admin connection
--workspace_connections {"anthropic-workspace": "Customer Service"} Optional. Maps each workspace connection to its workspace name. Without it, the job skips message_batches and files.
--reference_data_path s3://<your-bucket>/<prefix>/ Location of your business data
--start_date 2026-10-01 First day to load on the first run
  1. Choose Save.

Create the materialized view job

  1. On the AWS Glue console, choose ETL jobs, and then choose Script editor.
  2. For Engine, choose Spark. Choose Upload script, select anthropic_usage_mvs.py, and choose Create script.
  3. On the Job details tab, for Name, enter anthropic-usage-mvs. For IAM Role, choose the same role. For Glue version, choose Glue 6.0 (AWS Glue materialized views require AWS Glue 5.1 or later).
  4. Expand Advanced properties. Under Job parameters, add --datalake-formats with the value iceberg, and --conf with the same value as the ETL job. This job reads only from the table bucket, so it doesn’t need connections or other parameters.
  5. Choose Save.

For more information about job parameters, see Using job parameters in AWS Glue jobs.

Run and schedule the pipeline

On the ETL jobs page, run anthropic-usage-etl. After it succeeds, run anthropic-usage-mvs, which creates the views on its first run and refreshes them on later runs.

To keep the views current, create an AWS Glue workflow that runs the ETL job daily at 06:30 UTC, after Anthropic’s daily buckets close, and then runs the materialized view job. Alternatively, add SCHEDULE REFRESH EVERY 24 HOURS to each CREATE MATERIALIZED VIEW statement so that AWS Glue refreshes the views on a schedule, and schedule only the ETL job.

Answer the business questions with Amazon Athena

After you execute the following Glue scripts, in the Athena query editor, choose the catalog s3tablescatalog/amzn-s3-demo-table-bucket and the database mart. The results in this section come from the demo organization. The business datasets are samples.

Which business units are driving AI spend?

SELECT week_start, business_unit, spend_usd, prev_week_spend_usd
FROM weekly_spend_by_business_unit
WHERE week_start = (SELECT max(week_start) FROM weekly_spend_by_business_unit)
ORDER BY spend_usd DESC;

Is the spend paying off?

SELECT outcome_date, spend_usd, completed_resolutions, qa_score_pct, cost_per_resolution_usd
FROM unit_cost
WHERE business_unit = 'Customer Service'
ORDER BY outcome_date;
Athena query results for the unit_cost view showing daily spend and cost per resolution for Customer Service

Figure 8: Cost per resolution over time for Customer Service

Are any active API keys owned by employees who have left?

SELECT key_name, key_type, workspace, creator_status, last_used, output_tokens
FROM access_review
WHERE review_candidate
ORDER BY output_tokens DESC;
Athena query results for the access_review view listing active API keys whose creators have left the company

Figure 9: Active API keys owned by employees who have left

The query returns two keys, support-legacy in Customer Service and docproc-batch-legacy in Document Processing. Both are legacy keys, created by an employee who has since left, and both were used the previous day. A departed creator doesn’t mean that a key is misused. It identifies keys whose service ownership should be confirmed, for example by moving the workload to a service-account key, before the old key is disabled.

Part 3: Visualize AI spend and governance in AWS Quick

AWS Quick is a generative AI assistant for work. It helps employees find insights, conduct deep research, automate tasks, and take action across their business applications, bringing chat agents, research, workflow automation, and business intelligence (BI) together in one place. Its BI capability, AWS Quick Sight, turns data into interactive dashboards. With generative BI, you can build a multi-sheet dashboard from a natural language prompt or ask questions of your data in plain language.

Allow AWS Quick to access the table bucket

AWS Quick reads materialized views directly from the table bucket. Before you create a dataset, an AWS Quick administrator allows Quick to access the bucket:

  1. In AWS Quick, open Manage account.
  2. Under Permissions, choose AWS resources.
  3. Select Amazon S3 Tables, choose Select S3 table buckets, select the amzn-s3-demo-table-bucket table bucket, and choose Finish.

    AWS Quick Manage account permissions page granting access to the Amazon S3 table bucket

    Figure 10: Granting AWS Quick access to the table bucket

Without this step, creating the data source fails with a message that AWS Quick doesn’t have permission to access the database.

Create datasets from the materialized views

Create one dataset for each view that the dashboard uses:

  1. Choose Data, then Create dataset, and then Create data source.
  2. Choose Amazon S3 Tables. Enter a data source name, such as anthropic-usage, and the table bucket ARN, for example arn:aws:s3tables:<region>:<account-id>:bucket/amzn-s3-demo-table-bucket. Choose Create data source.
  3. For Namespace, choose mart. Select weekly_spend_by_business_unit and choose Select.
  4. Choose Directly query your data, and then Edit/Preview data. Check the preview and choose Save & publish.
  5. Repeat these steps for unit_cost, and select the anthropic-usage data source that you created instead of creating a new one.
AWS Quick dataset creation using the Amazon S3 Tables data source and the mart namespace views

Figure 11: Creating datasets from the materialized views in AWS Quick

Because the datasets query the views directly, the dashboard shows the latest results after each refresh of the materialized views. You don’t need a separate refresh schedule in AWS Quick.

Generate the analysis from a prompt

Instead of building each visual by hand, describe the review that leadership wants and let AWS Quick generate the analysis. On the Analyses page, choose Generate analysis. Choose Add data, select both datasets, and enter a prompt such as the following:

Create a simple weekly AI spend review for retail leadership, titled "Weekly AI Spend Review", with two sheets and no more than four visuals per sheet.

Spend sheet: each row of weekly_spend_by_business_unit is one business unit in one week. Filter the whole sheet to the most recent week_start only, never sum across weeks. Show a KPI of total spend_usd for that week compared with total prev_week_spend_usd, a horizontal bar chart of spend_usd by business_unit sorted from highest to lowest, and a bar chart of change_usd by business_unit. Add a business unit filter control.

Value sheet: Customer Service only, by outcome_date. Show cost_per_resolution_usd as US dollars with 4 decimal places in a KPI (average) and a line chart, a line chart of qa_score_pct, and a combo chart with spend_usd as bars and completed_resolutions as a line.

Keep sheet descriptions to one short plain sentence.
AWS Quick Generate analysis page with the weekly AI spend review prompt entered

Figure 12: Generating the analysis from a natural language prompt

Choose Preview analysis outline. AWS Quick reviews the columns and statistics of each dataset and proposes a plan with filter controls, sheets, and the visuals on each sheet. Review the plan, choose Edit if you want to change it, and then choose Generate.

AWS Quick analysis outline proposing sheets, filter controls, and visuals before generation

Figure 13: Previewing the proposed analysis outline

Describe the shape of your data in the prompt. The weekly_spend_by_business_unit view has one row per business unit per week. When our first prompt only asked to compare spend with the previous week, the generated analysis added all weeks together. Asking for the most recent week only fixed it.

Review the dashboard

The Spend sheet shows which business units are driving AI spend.

AWS Quick Spend sheet showing weekly AI spend by business unit with a KPI and bar charts

Figure 14: The Spend sheet showing AI spend by business unit

The Value sheet shows whether the spend is paying off.

AWS Quick Value sheet showing cost per resolution, QA score, and spend against completed resolutions for Customer Service

Figure 15: The Value sheet showing whether the spend is paying off

Publish and share the dashboard

Choose Publish to create a dashboard from the analysis, and share it with leadership. Viewers can filter and explore the dashboard without access to the analysis or the datasets behind it. To have the review arrive before the weekly meeting, schedule an email report from the dashboard.

Go further

This dashboard answers leadership’s questions with two datasets and a short prompt, but the same connector data supports much more. For advanced use cases, use the Agent Toolkit for AWS with your preferred AI coding agent to build a richer version of this solution through natural language. The following dashboard compares the price per million tokens across models, shows how much prompt caching saves, and lists the API keys to revoke. We generated the entire data pipeline and this dashboard with Kiro and the Agent Toolkit for AWS.

Advanced AWS Quick dashboard comparing price per million tokens across models, prompt caching savings, and API keys to revoke

Figure 16: A richer dashboard built with the Agent Toolkit for AWS

Considerations

  • Report time windows: Set starting_at for every usage and cost read. Daily buckets include only completed days. Use bucket_width = '1h' for the current day.
  • API key scope: An Admin API key reads organization data but not workspace data such as models, message batches, or files, and a workspace API key reads only its workspace. Use one connection per key, and one set of connections per Anthropic organization.
  • Rate limits: The Anthropic Admin API limits request rates. Use bounded time windows and scheduled incremental reads rather than large historical reads.
  • AWS Glue materialized views: AWS Glue materialized views require AWS Glue 5.1 or later and iam:PassRole for the role that refreshes them. Definitions must be deterministic, and in our testing views with a WITH clause failed to refresh, so use inline subqueries.
  • Security: Grant the AWS Glue role read access only to the secrets it needs, rotate Anthropic API keys regularly, and restrict access to curated tables.

Clean up

To avoid ongoing charges, delete the resources you created: the AWS Glue jobs, workflow, and connections. The Secrets Manager secrets. The materialized views, tables, namespaces, and table bucket in Amazon S3 Tables. The reference data and scripts in Amazon S3. You can also remove the dashboards and datasets that you created in AWS Quick. Consider revoking any Anthropic API keys you created for this walkthrough.

Conclusion

In this post, we showed how to use the AWS Glue connector for Anthropic to bring Anthropic usage, cost, and access data into AWS, store it as Apache Iceberg tables in Amazon S3 Tables, and keep business-ready results current with materialized views. With Amazon Athena, the retailer can see which business units drive AI spend, whether that spend pays off, and which API keys need an ownership review. Using AWS Quick, we used natural language to create dashboards.

To get started, see Anthropic connection options in the AWS Glue Developer Guide. To browse the other connection types that AWS Glue supports, including the new native connectors for SaaS applications, see Available connections.


About the authors

Daniyal Alam

Daniyal Alam

Daniyal is a Software Development Engineer at AWS. He is passionate about the data foundation behind generative AI, building data integration services that connect customers’ SaaS applications, databases, and data warehouses to their analytics and AI workloads on AWS. Outside of work, Daniyal enjoys cooking, driving, weightlifting, and getting outdoors to snowboard and hike.

David Zhang

David Zhang

David is a Senior Specialist Solutions Architect specializing in Data & AI at AWS. He focuses on designing and implementing open lakehouse architectures and agentic AI solutions. He is an active speaker at AWS events and contributes to technical publications and open-source initiatives. He is also the co-author of Apache Iceberg on AWS book. Outside of work, David enjoys staying active through volleyball, tennis, and basketball.

Kamen Sharlandjiev

Kamen Sharlandjiev

Kamen is a Pr. Big Data and ETL Solutions Architect, MWAA and AWS Glue ETL expert. He’s on a mission to make life easier for customers who are facing complex data integration and orchestration challenges. His secret weapon? Fully managed AWS services that can get the job done with minimal effort.

Shrey Malpani

Shrey Malpani

Shrey is a Senior Product Manager Technical at Amazon Web Services (AWS), where he works at the intersection of distributed data processing and data integration. He is focused on building and scaling data integration and data management capabilities across services like AWS Glue, Amazon EMR, and Amazon Redshift that help customers build AI-ready data platforms for their analytics and machine learning workflows.

Joju Eruppanal

Joju Eruppanal

Joju leads engineering teams at AWS, building foundational capabilities for agentic data processing. He helps customers and their agents process and work with data in the cloud. Outside of work, Joju enjoys spending time with his family.

The collective thoughts of the interwebz