How Cloudflare runs machine learning inference in microseconds

Post Syndicated from Austin Hartzheim original http://blog.cloudflare.com/how-cloudflare-runs-ml-inference-in-microseconds/
How Cloudflare runs machine learning inference in microseconds

How Cloudflare runs machine learning inference in microseconds

Cloudflare executes an array of security checks on servers spread across our global network. These checks are designed to block attacks and prevent malicious or unwanted traffic from reaching our customers’ servers. But every check carries a cost – some amount of computation, and therefore some amount of time must be spent evaluating every request we process. As we deploy new protections, the amount of time spent executing security checks increases.

Latency is a key metric on which CDNs are evaluated. Just as we optimize network latency by provisioning servers in close proximity to end users, we also optimize processing latency – which is the time spent processing a request before serving a response from cache or passing the request forward to the customers’ servers. Due to the scale of our network and the diversity of use-cases we serve, our edge software is subject to demanding specifications, both in terms of throughput and latency.

Cloudflare's bot management module is one suite of security checks which executes during the hot path of request processing. This module calculates a variety of bot signals and integrates directly with our front line servers, allowing us to customize behavior based on those signals. This module evaluates every request for heuristics and behaviors indicative of bot traffic, and scores every request with several machine learning models.

To reduce processing latency, we've undertaken a project to rewrite our bot management technology, porting it from Lua to Rust, and applying a number of performance optimizations. This post focuses on optimizations applied to the machine-learning detections within the bot management module, which account for approximately 15% of the latency added by bot detection. By switching away from a garbage collected language, removing memory allocations, and optimizing our parsers, we reduce the P50 latency of the bot management module by 79μs – a 20% reduction.

Engineering for zero allocations

Writing software without memory allocation poses several challenges. Indeed, high-level programming languages often trade memory management for productivity, abstracting away the details of memory management. But, in those details, are a number of algorithms to find contiguous regions of free memory, handle fragmentation, and call into the kernel to request new memory pages. Garbage collected languages incur additional costs throughout program execution to track when memory can be freed, plus pauses in program execution while the garbage collector executes. But, when performance is a critical requirement, languages should be evaluated for their ability to meet performance constraints.

Stack allocation

One of the simplest ways to reduce memory allocations is to work with fixed-size buffers. Fixed-sized buffers can be placed on the stack, which eliminates the need to invoke heap allocation logic; the compiler simply reserves space in the current stack frame to hold local variables. Alternatively, the buffers can be heap-allocated outside the hot path (for example, at application startup), incurring a one-time cost.

Arrays can be stack allocated:

let mut buf = [0u8; BUFFER_SIZE];

Vectors can be created outside the hot path:

let mut buf = Vec::with_capacity(BUFFER_SIZE);

To demonstrate the performance difference, let's compare two implementations of a case-insensitive string equality check. The first will allocate a buffer for each invocation to store the lower-case version of the string. The second will use a buffer that has already been allocated for this purpose.

Allocate a new buffer for each iteration:

fn case_insensitive_equality_buffer_with_capacity(s: &str, pat: &str) -> bool {
	let mut buf = String::with_capacity(s.len());
	buf.extend(s.chars().map(|c| c.to_ascii_lowercase()));
	buf == pat
}

Re-use a buffer for each iteration, avoiding allocations:

fn case_insensitive_equality_buffer_with_capacity(s: &str, pat: &str, buf: &mut String) -> bool {
	buf.clear();
	buf.extend(s.chars().map(|c| c.to_ascii_lowercase()));
	buf == pat
}

Benchmarking the two code snippets, the first executes in ~40ns per iteration, the second in ~25ns. Changing only the memory allocation behavior, the second implementation is ~38% faster.

Choice of algorithms

Another strategy to reduce the number of memory allocations is to choose algorithms that operate on the data in-place and store any necessary state on the stack.

Returning to our string comparison function from above, let's rewrite it operate completely on the stack, and without copying data into a separate buffer:

fn case_insensitive_equality_buffer_iter(s: &str, pat: &str) -> bool {
	s.chars().map(|c| c.to_ascii_lowercase()).eq(pat.chars())
}

In addition to being the shortest, this function is also the fastest. This function benchmarks at ~13ns/iter, which is just slightly slower than the 11ns used to execute eq_ignore_ascii_case from the standard library. And the standard library implementation similarly avoids buffer allocation through use of iterators.

Testing allocations

Automated testing of memory allocation on the critical path prevents accidental use of functions or libraries which allocate memory. dhat is a crate in the Rust ecosystem that supports such testing. By setting a new global allocator, dhat is able to count the number of allocations, as well as the number of bytes allocated on a given code path.

/// Assert that the hot path logic performs zero allocations.
#[test]
fn zero_allocations() {
	let _profiler = dhat::Profiler::builder().testing().build();

	// Execute hot-path logic here.

	// Assert that no allocations occurred.
	dhat::assert_eq!(stats.total_blocks, 0);
	dhat::assert_eq!(stats.total_bytes, 0);
}

It is important to note, dhat does have the limitation that it only detects allocations in Rust code. External libraries can still allocate memory without using the Rust allocator. FFI calls, such as those made to C, are one such place where memory allocations may slip past dhat's measurements.

Zero allocation decision trees

CatBoost is an open-source machine learning library used within the bot management module. The core logic of CatBoost is implemented in C++, and the library exposes bindings to a number of other languages – such as C and Rust. The Lua-based implementation of the bot management module relied on FFI calls to the C API to execute our models.

By removing memory allocations and implementing buffer re-use, we optimize the execution duration of the sample model included in the CatBoost repository by 10%. Our production models see gains up to 15%.

Optimize for single-document evaluation

By optimizing CatBoost to evaluate a single set of features at a time, we reduce memory allocations and reduce latency. The CatBoost API has several functions which are optimized for evaluating multiple documents at a time, but this API does not benefit our application where requests are evaluated in the order they are received, and delaying processing to coalesce batches is undesirable. To support evaluation of a variable number of documents, the CatBoost implementation allocates vectors and iterates over the input documents, writing them into the vectors.

TVector<TConstArrayRef<float>> floatFeaturesVec(docCount);
TVector<TConstArrayRef<int>> catFeaturesVec(docCount);
for (size_t i = 0; i < docCount; ++i) {
    if (floatFeaturesSize > 0) {
        floatFeaturesVec[i] = TConstArrayRef<float>(floatFeatures[i], floatFeaturesSize);
    }
    if (catFeaturesSize > 0) {
        catFeaturesVec[i] = TConstArrayRef<int>(catFeatures[i], catFeaturesSize);
    }
}
FULL_MODEL_PTR(modelHandle)->Calc(floatFeaturesVec, catFeaturesVec, TArrayRef<double>(result, resultSize));

To evaluate a single document, however, CatBoost only needs access to a reference to contiguous memory holding feature values. The above code can be replaced with the following:

TConstArrayRef<float> floatFeaturesArray = TConstArrayRef<float>(floatFeatures, floatFeaturesSize);
TConstArrayRef<int> catFeaturesArray = TConstArrayRef<int>(catFeatures, catFeaturesSize);
FULL_MODEL_PTR(modelHandle)->Calc(floatFeaturesArray, catFeaturesArray, TArrayRef<double>(result, resultSize));

Similar to the C++ implementation, the CatBoost Rust bindings also allocate vectors to support multi-document evaluation. For example, the bindings iterate over a vector of vectors, mapping it to a newly allocated vector of pointers:

let mut float_features_ptr = float_features
   .iter()
   .map(|x| x.as_ptr())
   .collect::<Vec<_>>();

But in the single-document case, we don't need the outer vector at all. We can simply pass the inner pointer value directly:

let float_features_ptr = float_features.as_ptr();

Reusing buffers

The previous API in the Rust bindings accepted owned Vecs as input. By taking ownership of a heap-allocated data structure, the function also takes responsibility for freeing the memory at the conclusion of its execution. This is undesirable as it forecloses the possibility of buffer reuse. Additionally, categorical features are passed as owned Strings, which prevents us from passing references to bytes in the original request. Instead, we must allocate a temporary String on the heap and copy bytes into it.

pub fn calc_model_prediction(
	&self,
	float_features: Vec<Vec<f32>>,
	cat_features: Vec<Vec<String>>,
) -> CatBoostResult<Vec<f64>> { ... }

Let's rewrite this function to take &[f32] and &[&str]:

pub fn calc_model_prediction_single(
	&self,
	float_features: &[f32],
	cat_features: &[&str],
) -> CatBoostResult<f64> { ... }

But, we also execute several models per request, and those models may use the same categorical features. Instead of calculating the hash for each separate model we execute, let's compute the hashes first and then pass them to each model that requires them:

pub fn calc_model_prediction_single_with_hashed_cat_features(
	&self,
	float_features: &[f32],
	hashed_cat_features: &[i32],
) -> CatBoostResult<f64> { ... }

Summary

By optimizing away unnecessary memory allocations in the bot management module, we reduced P50 latency from 388us to 309us (20%), and reduced P99 latency from 940us to 813us (14%). And, in many cases, the optimized code is shorter and easier to read than the unoptimized implementation.

These optimizations were targeted at model execution in the bot management module. To learn more about how we are porting bot management from Lua to Rust, check out this blog post.
Power LED Side-Channel Attack

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/power-led-side-channel-attack.html

This is a clever new side-channel attack:

The first attack uses an Internet-connected surveillance camera to take a high-speed video of the power LED on a smart card reader­—or of an attached peripheral device—­during cryptographic operations. This technique allowed the researchers to pull a 256-bit ECDSA key off the same government-approved smart card used in Minerva. The other allowed the researchers to recover the private SIKE key of a Samsung Galaxy S8 phone by training the camera of an iPhone 13 on the power LED of a USB speaker connected to the handset, in a similar way to how Hertzbleed pulled SIKE keys off Intel and AMD CPUs.

There are lots of limitations:

When the camera is 60 feet away, the room lights must be turned off, but they can be turned on if the surveillance camera is at a distance of about 6 feet. (An attacker can also use an iPhone to record the smart card reader power LED.) The video must be captured for 65 minutes, during which the reader must constantly perform the operation.

[…]

The attack assumes there is an existing side channel that leaks power consumption, timing, or other physical manifestations of the device as it performs a cryptographic operation.

So don’t expect this attack to be recovering keys in the real world anytime soon. But, still, really nice work.

More details from the researchers.

Welcome to Speed Week 2023

Post Syndicated from Sam Marsh original http://blog.cloudflare.com/welcome-to-speed-week-2023/

Welcome to Speed Week 2023

Welcome to Speed Week 2023

What we consider ‘fast’ is changing. In just over a century we’ve cut the time taken to travel to the other side of the world from 28 days to 17 hours. We developed a vaccine for a virus causing a global pandemic in just one year – 10% of the typical time. AI has reduced the time taken to complete software development tasks by 55%. As a society, we are driven by metrics – and the need to beat what existed before.

At Cloudflare we don't focus on metrics of days gone by. We’re not aiming for “faster horses”. Instead we are driven by questions such as “What does it actually look like for users?”, “How is this actually speeding up the Internet?”, and “How does this make the customer faster?”.

This innovation week we are helping users measure what matters. We will cover a range of topics including how we are fastest at Zero Trust, have the fastest network and a deep dive on cache purge and why global purge latency mightn’t be the gold star it's made out to be. We’ll also cover why Time to First Byte is generally a bad measurement. And what you should care about instead.

Woven amongst these topics are a number of great new products and features that genuinely make you and your customers faster. From API acceleration and end-to-end Brotli 11 compression, to reducing page load times by 30% with one-click. Plus a brand new home for application performance.

This week we will help you measure what matters. We’ll help you gain insight into your performance, from Zero Trust and API’s to websites and applications. And finally we’ll help you get faster. Quickly.

We are proving we are the fastest at what we do. And we are making it as easy as possible for our users to attain those numbers.

Welcome to Speed Week.

More megapixels?

You don't have to go far in the real world to find examples of highly-touted metrics that likely don't capture what you really care about.

If you read the announcements each year you’d be forgiven for believing smartphones have devolved into cameras with apps and an antenna. With each new model announced the press releases reference megapixel improvements between the previous and latest model.

The number of megapixels alone does not guarantee better image quality. Factors such as sensor size, lens quality, image processing algorithms, and low-light performance also play significant roles in determining the overall camera performance. This has been a widely accepted view for over a decade now, so why do companies keep pushing it as a metric – and why do users feel it's important?

Similarly, marketing collateral from Internet Service Providers would have you believe that “bandwidth is king”.

However it has been categorically proven that bandwidth is not the sole indicator of speed. Just two months ago we published a blog on “Making home Internet faster has little to do with speed”, concluding “While bandwidth plays a part, the latency of the connection – the real Internet “speed” – is more important”. The post references a recent paper by two researchers from MIT which supports this point, showing the point of diminishing returns is around 20Mbps for when more bandwidth doesn't mean a webpage loads much faster.

Again, the advertised, and generally accepted comparison metric amongst consumers, is incorrect. More bandwidth does not equal faster Internet speeds.

Simply put – are you really measuring what matters to you when reviewing your product choices and vendors? Or on reflection have your choices been influenced by dogma for far too long?

Measuring what matters on the Internet

Similarly to the smartphone and ISP industries, we at Cloudflare operate in industries where users often compare us against competitors using metrics that likely don't measure what matters to them.

Large enterprises use software to selectively shift traffic between Content Delivery Networks (CDNs) based on the lowest possible Time to First Byte (TTFB) score per region. This means if Cloudflare suddenly were to cut its TTFB in half in Africa, for example, we could see a huge influx of traffic in this region from these enterprise customers – likely not doing anything to improve the actual visitor experience of a website.

TTFB is often used as a measure of how quickly a web server responds to a request and common web testing services report it. The faster it is the better the web server (in theory). We have known for years, however, that TTFB is not on its own a fair reflection of real world performance.

Receiving the first byte isn't sufficient to determine a good end user experience as most pages have additional render blocking resources that get loaded after the initial document request. TTFB does not take into account multiplexing benefits of HTTP/2 and HTTP/3 which allow browsers to load files in parallel. It also doesn't account for features like Early Hints, Zaraz, Rocket Loader, HTTP/2 and soon HTTP/3 Prioritization which eliminate render blocking.

As Sitespect wrote last year, “TTFB is a measure of how fast a web server is able to respond to a request, and how long it takes for that request to traverse various layers of networking to reach a user’s browser. It is a measure of speed for delivery of content, but it is not a measurement for how long end-users are effectively waiting before they can start interacting with your website. TTFB completely ignores everything that happens after that network layer: loading, downloading of resources, rendering, etc. In other words, TTFB is not a user-centric measurement, it’s a networking measurement.”.

At Cloudflare we are all-in on Real User Monitoring (RUM) as the future of website performance. We’re investing heavily in it – both from an observation point of view and from an optimization one also. This week we will be releasing a series of new products aimed at helping users understand the actual experience of their end users (i.e. website visitors), and provide suggestions on how to improve it.

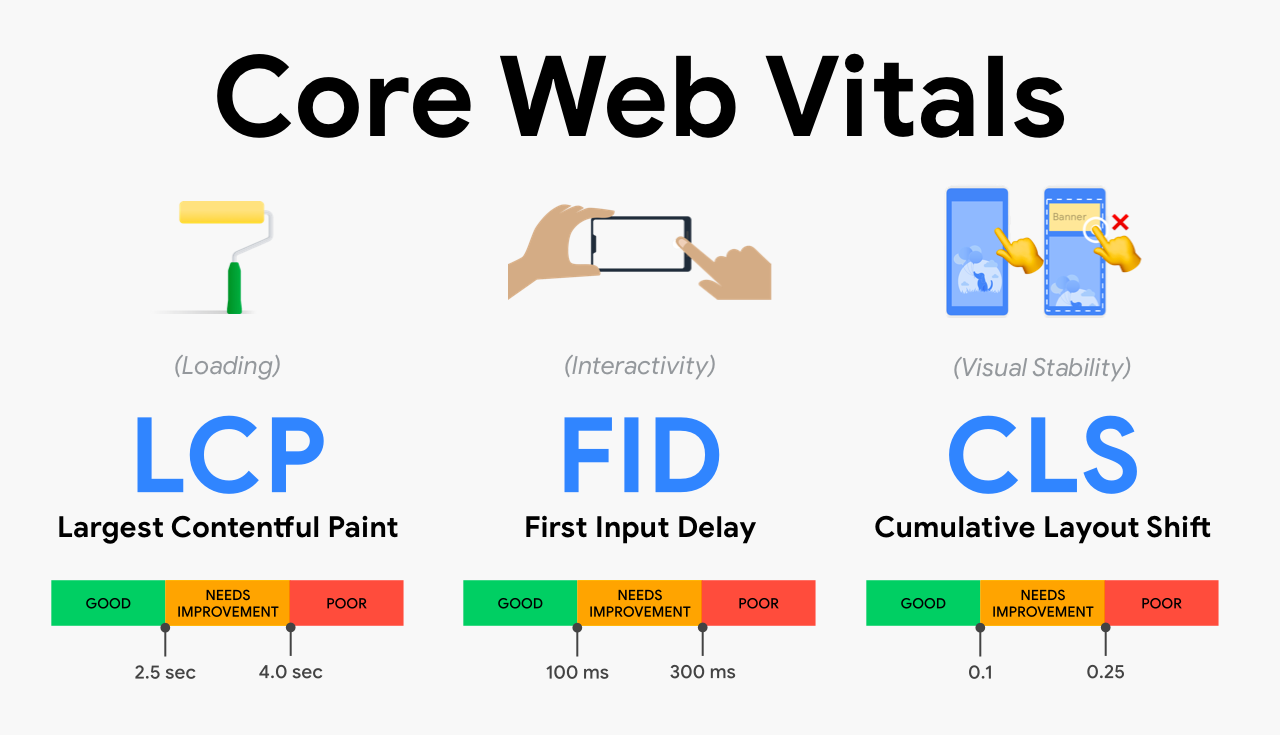
For those unfamiliar with RUM, we typically optimize websites for three main metrics – known as the “Core Web Vitals”. This is a set of key metrics which are believed to be the best and most accurate representation of a poorly performing website vs a well performing one. These key metrics are Largest Contentful Paint, First Input Delay and Cumulative Layout Shift.

Welcome to Speed Week 2023
Credit: https://addyosmani.com/blog/web-vitals-extension/

LCP measures loading performance; typically how long it takes to load the largest image or text block visible in the browser. FID measures interactivity. For example, the time between when a user clicks or taps on a button to when the browser responds and starts doing something. Finally, CLS measures visual stability. A good, or bad example of CLS is when you go to a website on your mobile phone, tap on a link and the page moves at the last second meaning you tap something you didn't want to. That would be a lower CLS score as its poor user experience.

Looking at these metrics gives us a good idea of how the end user is truly experiencing your website (RUM) vs. how quickly the nearest Cloudflare data center begins to return data (TTFB).

The other benefit of Real User Monitoring is it includes the speed advantage of new protocols and features designed to improve the customer experience. For example, Time to First Byte is a single connection between the client and the nearest Cloudflare server. This is nothing like how a web browser connects to a website, which uses multiplexing to fetch multiple files at the same time in parallel. There are also products like Early Hints which are designed to take advantage of the “server think time” to send instructions to the browser to begin loading readily-available resources while the server finishes compiling the full response.

In Speed Week we will be going deep into why TTFB is a bad metric to care about for websites and web applications, why RUM is the future, and a blog post on the latest Core Web Vital – “Interaction to Next Paint” (INP), and what it means to you as a business.

We will also be unveiling a brand-new product which will be the new home of application performance on Cloudflare. The new product will augment synthetic tests from various global locations with real user monitoring data to give administrators the best possible understanding of how their website is performing in the real world. This product will be available for all plan levels.

We’re the fastest, and we can prove it

It's no secret that Cloudflare is fast.

However it might not be obvious to the everyday reader just how fast we are, and in just how many areas.  Fastest compute. Fastest DNS. Fastest network. Fastest Zero Trust Network Access (ZTNA). Fastest Secure Web Gateway (SWG). Fastest object storage. And we’re finding areas we are not empirically the fastest and looking to prove we are number one.

We’re also finding ways to migrate customers from legacy providers and applications to Cloudflare as fast as possible. These legacy vendors have locked in companies using confusing terminology and esoteric features, trapping them on sub-par products and making them too afraid to move away. We’re helping those customers escape. Super Slurper helps customers move away from S3, Turpentine helps migrate legacy VCL setups to Cloudflare, and our Descaler program helps to migrate customers from Zscaler to Cloudflare in a matter of hours. We are building tools and products to help those customers who want to move to the fastest network but are locked in.

In Speed Week we’ll cover the latest on these programs and how we are relentlessly pushing to make the migration process as quick and easy as possible for customers who want to move to Cloudflare and put their business on the fastest network around.

Performance matters, whatever the product area

Generally when you hear of performance improvements it's typically through the lens making websites faster. But speed comes in many forms. Take Zero Trust as an example.

Measuring Zero Trust performance matters because it impacts your employees' experience and their ability to get their job done. Whether it’s accessing services through access control products, connecting out to the public Internet through a Secure Web Gateway, or securing risky external sites through Remote Browser Isolation, all of these experiences need to be frictionless. But what if your company's Secure Web Gateway is in London and you are in Johannesburg? This can mean a painful, slow, and frustrating employee experience whilst they wait for traffic to be sent to and from London. Slack becomes slow. Zoom becomes slow. Employees become frustrated.

The bigger concern, however, is not knowing of these performance issues. For example, if each of your employees are physically located in an office and the connection to critical business systems like Salesforce or Workday worsens, the likelihood is it will become evident quickly. But what about in a remote workforce with employees globally distributed? As a business, you need the ability to understand how your employees are experiencing critical business systems and identify any connection and performance issues they may be experiencing to ensure they get addressed quickly. In Speed Week we’ll unveil our latest Zero Trust offering which will give CIOs and businesses incredible insight into the performance experience of their workforce.

Speed Week will show Cloudflare is the fastest Zero Trust provider. Our analysis will provide updated benchmark comparisons and include additional competitors to show how we outperform everyone to give employees the fastest Zero Trust experience.

Another area we will shine a spotlight on this week is cache purge. When you think of CDNs it's common to look at them as a large distributed cache. Visitor-requested files are retrieved from an origin and stored on globally distributed CDN servers. This allows visitors to download the file in the quickest possible time by retrieving it from their nearest Cloudflare data center rather than having to traverse the Internet to and from the origin. TTFB will measure the time taken to receive a single file from the nearest location. RUM will measure the time it takes to receive multiple files, cached and uncached, and put them together into the webpage requested. But what about when the file changes on origin?

In the scenario where a business is hosting a pricebook as a downloadable file on its website, it is very important to understand how long it takes to remove old copies from Cloudflare cache to ensure customers don't see incorrect prices. This is where measuring cache purge times becomes important. The time taken to remove the invalidated file (old file) from every server in every data center in the CDN is known as the ‘global purge time’. In Speed Week we will explain how we have built our new cache purge architecture to be lightning-fast and what the performance numbers are as a result (spoiler: they are insanely fast).

These are just a few examples of what we have in store for the week. We also have blogs on AI, API acceleration, developer platform, networking, protocols, compression, streaming, UI optimization and more.

Speed at the heart of Cloudflare

At Cloudflare we put performance at the heart of everything we do.

Make sure to follow the Cloudflare blog and social media accounts for all of the week's news, and join us on Cloudflare TV each day for a live discussion of the day's announcements.

Welcome to Speed Week.

Служебен обмен на данни в електронното управление

Post Syndicated from Bozho original https://blog.bozho.net/blog/4106

През 2015 г. електронното управление е доникъде. Е-услуги имат общо взето само НАП (такива, които се ползват, имам предвид), а служебното събиране на данни между администтациите, предвидено още от 2009 г. в закона почти не се случва.

Министерство на транспорта е възложило изграждане на система за обмен на данни между системи и регистри (RegiX). Но тя не е заработила на практика и няма изглед да заработи, защото администрациите отказват да го ползват – бил „незаконен“. Дори в случаите, в които някой се престраши, най-важните първични администратори – ГРАО и МВР изискват сключване на тристранни споразумения и масово отказват достъп по своя преценка.

Тогава правим две изменения, които да отключат процеса – в Закона за електронното управление забраняваме допълнителните споразумения, а в наредбата към него уреждаме използването на системата за обмен на данни като един от възможните начини за служебно събиране на данни.

Оттогава служебният обмен расте всеки месец и на гражданите се спестяват някои „разходки“. Но докато вече всичко по обмена на данни е ясно и макар администрациите да го ползват, те продължават да искат удостоверения и бележки, защото казват „в нашия закон пише, че трябва да съберем тези данни от заявителя“.

Затова в следващите седмици ще гласуваме следващата стъпка – приравняване на служебната справка на предоставени от заявителя удостоверения, така че дори в някой закон и наредба да пише „представя удостоверение“, това да не е пречка пред спестяването на административната тежест. Не само това, а въвеждаме удостоверяване на тези справки с електронен печат, за да няма оправдания „аз как да знам, че тези електронни данни са истински“.

Даволът е в детайлите – и техническите, и нормативните, и организационно-човешките. И една от причините да съм в парламента е, че такива детайли там има всяка седмица, а за да има електронно управление по сектори, понякога зависи от две алинеи и даже от две думи.

Материалът Служебен обмен на данни в електронното управление е публикуван за пръв път на БЛОГодаря.

Седмицата (12–17 юни)

Post Syndicated from Йовко Ламбрев original https://www.toest.bg/sedmitsata-12-17-june/

Седмицата (12–17 юни)

Според теорията на преговорите една от най-устойчивите сделки е тази, при която всички са малко недоволни. Парадокс на нашата действителност е, че най-често недоволството е в повече. Навсякъде.

Та с много изначално недоволство и последвали престъргвания и поскърцвания новото българско правителство избута първата си седмица. И повече от очевидно е, че никой не възнамерява да му остави 100 дни комфорт. Бесовете и сенките в българската политика не са се укротили, даже напротив. Особено озверяха след този ход, който очевидно обърка доста планове. Едно със сигурност е ясно – разместването на пластовете ще е придружено с още трусове. И жертви… В този ред на размисли първата седмица на кабинета „Денков“ се оказа последната на Иван Гешев като главен прокурор.

За тези и други важни теми от изминалата седмица прочетете в анализа на Емилия Милчева, озаглавен „Залезът на българските божества“.

Но докато сме на темата с бесовете, да не пропуснем нещо важно. В българския обществен живот винаги е имало субекти, които тровят ежедневието и се захранват с внимание, създавайки скандали. Напоследък в тази токсична роля е „Възраждане“, чиито активисти през седмицата се опитаха да спретнат шумно „аутодафе“ на филм в София и Пловдив. С хомофобски аргументи. И с фашистки подход.

С риск да захраним тази формация с още малко внимание, повече от наложителни са институционални мерки срещу нея. Отговорност на медиите, особено националните, е да поспестят безкритично отворените микрофони, които така щедро ѝ предоставят. Различната гледна точка невинаги заслужава внимание. И сме длъжни да я заглушим и да ѝ се противопоставим фронтално, ако пропагандира омраза. Нека не се заблуждаваме, че късопишещите ще водят някакви площадни битки в София – тяхната борба е за съзнанията на хората в периферията.

Това беше само началото. Там, където горят книги, по-късно ще горят и хора.

Хайнрих Хайне

На темата с разцвета и институционализирането на хомофобията, а и на антиевропейската пропаганда в най-общ план в България е посветен и материалът на Светла Енчева „Еврото ли ще е следващият „джендър“?

И като заговорихме за отговорността на националните медии, ето какво е написал във Facebook профила си дългогодишният водещ по БНР Петър Волгин на 1 февруари т.г., в Деня за почит към жертвите на комунизма: „Достатъчно е да погледаш само десетина минути някой нахален и неумен богаташ като Хампарцумян, за да разбереш защо е трябвало да има Народен съд.“

По повод тези думи 102-годишна жена е завела гражданско дело срещу журналиста за нанесени неимуществени вреди, изразяващи се в „душевни болки и страдания“, съобщава Клуб Z. Столетницата е загубила съпруга си по време на т.нар. Народен съд през 1944 г., когато той и всички първенци от селото им „са били убити и хвърлени в масов гроб без съд, без присъда и без каквото и да е деяние от тях, освен че са изпълнили дълга си да се явят на повикватeлна в армията“. Две години по-късно той е обявен за „безследно изчезнал“. Тя остава сама с двегодишния им син. Животът на двамата по време на комунистическия режим е тежък, на сина ѝ не е позволено да учи в университет, семейството е считано за „врагове на народа“ и е следено от Държавна сигурност.

Когато дойдоха промените, се надявах, че ще има някаква справедливост за жертвите на комунизма. И ако не извинение от палачите и техните наследници, то поне признание от обществото, че това, което ни е било причинено, е несправедливо, нечовешко и жестоко. За съжаление, в обществото са налице противоположни мнения, като все по-гласовити стават някои граждани, които не само че не признават престъпния характер на комунистическия режим, но дори го и възхваляват.

„Във времена, в които бъдещето на демокрацията в България изглежда объркано и все по-обвързано със съдебната система, има едно място, където правораздаването се пресича с архитектурата, при това буквално“, пише Анета Василева в новата си статия за „Тоест“, която е посветена на състоянието на затворите и условията, в които живеят лишените от свобода. Един прелюбопитен материал за властта на пространството и как пространствата всъщност формират хората. Не го пропускайте!

Сред любимите ми рубрики в „Тоест“ е „Научни новини“, водена от Михаил Ангелов. А тазседмичната му статия е една от най-интересните в поредицата. В нея ще прочетете как с помощта на вирус и генна модификация може да се постигне контрол над популацията на бездомните котки, какво сънуват гълъбите, как с нови технологии се осигурява възможност за успешна сърдечна трансплантация дори от донор, чието кръвообращение е спряло, и как т.нар. изкуствен интелект помага за усъвършенстване на някои от базовите изчислителни задачи.

Завършваме седмицата с хубава книга. В рубриката „По буквите“ Зорница Христова реши да ни изненада с българския превод на стихосбирката на Ю Дзиен „Давам име на една врана“. Да оставим настрани факта, че рядко до четящите българи достига китайска литература, а още по-малко поезия. Още по-ценното е, че имаме възможност да прочетем един съвременен китайски поет, пишещ по актуалните теми от ежедневието, извън географските дистанции. Както казва Зорница,

не бива да гледаме на поезията на Ю Дзиен като на реалистична поезия, тоест като описваща реалността. Тя е по-скоро хипнотизирана от пълнокръвието на света, от изобилието на случващото се в него и описва именно този свой захлас.

Приятно четене!

Friday Squid Blogging: Squid Can Edit Their RNA

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/friday-squid-blogging-squid-can-edit-their-rna.html

This is just crazy:

Scientists don’t yet know for sure why octopuses, and other shell-less cephalopods including squid and cuttlefish, are such prolific editors. Researchers are debating whether this form of genetic editing gave cephalopods an evolutionary leg (or tentacle) up or whether the editing is just a sometimes useful accident. Scientists are also probing what consequences the RNA alterations may have under various conditions.

I sometimes think that cephalopods are aliens that crash-landed on this planet eons ago.

Another article.

As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.

Read my blog posting guidelines here.

Metasploit Weekly Wrap-Up

Post Syndicated from Alan David Foster original https://blog.rapid7.com/2023/06/16/metasploit-weekly-wrap-up-15/

Metasploit T-Shirt Design Contest

Metasploit Weekly Wrap-Up

In honor of Metasploit’s 20th anniversary, Rapid7 is launching special edition t-shirts – and we’re inviting members of our community to have a hand in its creation. The contest winner will have their design featured on the shirts, which will then be available to pick up at Black Hat 2023.

We will be accepting submissions from now through June 30! Contest details, design guidelines, and submission instructions here

New module content (12)

RPyC 4.1.0 through 4.1.1 Remote Command Execution

Authors: Aaron Meese and Jamie Hill-Daniel
Type: Auxiliary
Pull request: #17670 contributed by ajmeese7
AttackerKB reference: CVE-2019-16328

Description: Adds a new rpyc_rce module to exploit CVE-2019-16328 and achieve remote command execution as the vulnerable server’s service user.

Apache RocketMQ Version Scanner

Authors: Malayke and h00die
Type: Auxiliary
Pull request: #18075 contributed by h00die

Description: This PR adds a version scanner for Apache RocketMQ.

Symmetricom SyncServer Unauthenticated Remote Command Execution

Authors: Justin Fatuch Apt4hax, Robert Bronstein, and Steve Campbell
Type: Exploit
Pull request: #18077 contributed by sdcampbell
AttackerKB reference: CVE-2022-40022

Description: This adds an exploit for Symmetricom SyncServer appliances (S100-S300 series) vulnerable to an unauthenticated command injection in the hostname parameter in a request to the /controller/ping.php endpoint. The command injection vulnerability is patched in the S650 v2.2. Requesting the endpoint will result in a redirect to the login page; however, the command will still be executed, resulting in RCE as the root user.

TerraMaster TOS 4.2.06 or lower – Unauthenticated Remote Code Execution

Authors: IHTeam and h00die-gr3y
Type: Exploit
Pull request: #18063 contributed by h00die-gr3y
AttackerKB reference: CVE-2020-28188

Description: This adds an exploit for TerraMaster NAS devices running TOS 4.2.06 or prior. The logic in include/makecvs.php permits shell metacharacters through the Event parameter in a GET request, permitting the upload of a webshell without authentication. Through this, an attacker can achieve remote code execution as the user running the TOS web interface.

TerraMaster TOS 4.2.15 or lower – RCE chain from unauthenticated to root via session crafting.

Authors: h00die-gr3y and n0tme
Type: Exploit
Pull request: #18070 contributed by h00die-gr3y
AttackerKB reference: CVE-2021-45841

Description: This exploits a series of vulnerabilities including session crafting and command injection in TerraMaster NAS versions 4.2.15 and below to achieve unauthenticated RCE as the root user.

TerraMaster TOS 4.2.29 or lower – Unauthenticated RCE chaining CVE-2022-24990 and CVE-2022-24989

Authors: 0xf4n9x, Octagon Networks, and h00die-gr3y
Type: Exploit
Pull request: #18086 contributed by h00die-gr3y
AttackerKB reference: CVE-2022-24989

Description: This exploits an administrative password leak and command injection vulnerability on TerraMaster devices running TerraMaster Operating System (TOS) versions 4.2.29 and below to achieve unauthenticated RCE as the root user.

Zyxel IKE Packet Decoder Unauthenticated Remote Code Execution

Author: sf
Type: Exploit
Pull request: #18016 contributed by sfewer-r7
AttackerKB reference: CVE-2023-28771

Description: This adds an exploit for CVE-2023-28771 which is a remote, unauthenticated OS command injection in IKE service of several Zyxel devices. Successful exploitation results in remote command execution as the root user.

Oracle Weblogic PreAuth Remote Command Execution via ForeignOpaqueReference IIOP Deserialization

Authors: 14m3ta7k, 4ra1n, and Grant Willcox
Type: Exploit
Pull request: #17946 contributed by gwillcox-r7
AttackerKB reference: CVE-2023-21839

Description: This adds an exploit for CVE-2023-21839 which is an unauthenticated RCE in Oracle Weblogic. Successful exploitation results in remote code execution as the oracle user.

Three x86 Linux Fetch Payloads

Author: Spencer McIntyre
Type: Payload
Pull request: #18084

Description: Fetch and execute a x86 payload from an HTTP server. These modules were developed live on stream. Fetch based payloads offer a shorter path from command injection to a Metasploit session

Authors: Daniel López Jiménez (attl4s) and Simone Salucci (saim1z)
Type: Post
Pull request: #18022 contributed by attl4s

Description: This adds the post/windows/manage/make_token module which is capable of creating new tokens from known credentials and then setting them in a running instance of Meterpreter, which can allow that session to access resources it might not have previously been able to access.

Enhancements and features (11)

  • #17336 from smashery – This PR adds new code to simplify and standardize windows version checking and comparisons.
  • #17781 from araout42 – Adds support for module writers to supply a custom include_dirs array when using the MinGW library to compile payloads.
  • #17942 from cdelafuente-r7 – The script generated by the web_delivery module is blocked by the Antimalware Scan Interface (AMSI) on newer versions of windows. This PR includes an enhancement which allows the web_delivery module to bypass AMSI.
  • #17955 from jvoisin – Reduces the size of PHP payloads such as php/reverse_php.
  • #18050 from adfoster-r7 – Adds a new post/test/all module which will run all available post/test modules against the open session.
  • #18069 from sempervictus – This updates the LDAP server library to handle unbind requests.
  • #18089 from shellchocolat – Adds supports for masm output format when generating payloads.
  • #18106 from adfoster-r7 – This PR updates Meterpreter’s setg SessionTLVLogging true support to no longer truncate useful values such as payload UUIDs, file paths, executed commands etc.
  • #18109 from adfoster-r7 – Update test post modules to always have a clean, writable, and consistent test file system directory when running modules under the loadpath test/modules directory.
  • #18110 from adfoster-r7 – When running test modules that have been loaded by loadpath test/modules, any verbose printing logic generated will now be prefixed by the current test that is being run.
  • #18115 from adfoster-r7 – This PR updates unknown windows errors on python Meterpreter to include original error code.

Bugs fixed (15)

  • #18051 from adfoster-r7 – Adds additional skip calls to the test/post modules to ensure that only relevant test expectations are run against the specified session without crashes.
  • #18054 from bwatters-r7 – This PR fixes the issue where an ArgumentError was thrown on the FETCH_SRVHOST option when running the info command when using a fetch payload.
  • #18068 from smashery – Fixes a bug that caused multi/manage/shell_to_meterpreter to not break when win_transfer=VBS was set.
  • #18076 from smashery – This fixes a bug in the Windows Meterpreter’s memory free API.
  • #18083 from zeroSteiner – A bug has been fixed in the stdapi extension of Meterpreter when calling the stdapi_sys_process_memory_free command. This incorrectly handled memory, leading to a double free condition, which would crash Meterpreter. This has since been fixed.
  • #18090 from adfoster-r7 – The auxiliary/admin/kerberos/keytab EXPORT action will now consistently order exported entries.
  • #18097 from adfoster-r7 – This PR fixes Python Meterpreter sessions from crashing when extracting macOS network configuration when using the route or ipconfig commands.
  • #18098 from adfoster-r7 – This PR Fixes rex-text crashes when running ruby 3.3.
  • #18099 from adfoster-r7 – This PR fixes Python Meterpreter subprocess deadlock and file descriptor leak caused by the stdout/stderr file descriptors not being closed.
  • #18101 from adfoster-r7 – This PR fixes a Python Meterpreter macOS route command crash when ifconfig has a gateway name as a mac address separated by dots.
  • #18102 from adfoster-r7 – This PR adds a fix for false negatives on files not existing on windows python Meterpreter.
  • #18105 from adfoster-r7 – This PR fixes a bug when running the time command in msfconsole with complex commands.
  • #18108 from adfoster-r7 – Updates the test/services module to more consistently pass. This module is useful for developers contributing enhancements or new functionality to Meterpreter and other payloads. It is available after running loadpath test/modules.
  • #18111 from adfoster-r7 – This PR fixes an initialized constant error when Meterpreter registry key reads timeout.
  • #18112 from adfoster-r7 – This PR fixes a symlink test bug when running python Meterpreter on windows.

Documentation added (1)

  • #18058 from gwillcox-r7 – Adds additional details on how to navigate the Metasploit codebase.

You can always find more documentation on our docsite at docs.metasploit.com.

Get it

As always, you can update to the latest Metasploit Framework with msfupdate
and you can get more details on the changes since the last blog post from
GitHub:

If you are a git user, you can clone the Metasploit Framework repo (master branch) for the latest.
To install fresh without using git, you can use the open-source-only Nightly Installers or the
binary installers (which also include the commercial edition).

Registration for LPC 2023 is open

Post Syndicated from original https://lwn.net/Articles/934961/

The registration for this year’s Linux Plumbers Conference (LPC) is now open. It will be held November 13-15 in Richmond, Virginia in the US.
The attend page has all of the details. Meanwhile, some of the calls for proposals are still open, though the microconferences CFP is closed; this year’s proposed microconference topics are listed here. Those who want to attend should note:
“As usual we expect to sell our rather quickly so don’t delay your registration for too long!”

[$] Merging bcachefs

Post Syndicated from original https://lwn.net/Articles/934692/

The bcachefs filesystem, and the
process for getting it upstream, were the topics
of a session led remotely by
Kent Overstreet, creator of bcachefs, at the
2023 Linux Storage, Filesystem,
Memory-Management and BPF Summit
. He has also discussed bcachefs in
previous editions of the summit, first
in 2018
and at last year’s event;
in both of those cases, the question of getting bcachefs merged
into the mainline kernel came up, but that merge has not happened yet.
This time
around, though, Overstreet seemed
closer than ever to being ready to actually start that process.

Security and Human Behavior (SHB) 2023

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/06/security-and-human-behavior-shb-2023.html

I’m just back from the sixteenth Workshop on Security and Human Behavior, hosted by Alessandro Acquisti at Carnegie Mellon University in Pittsburgh.

SHB is a small, annual, invitational workshop of people studying various aspects of the human side of security, organized each year by Alessandro Acquisti, Ross Anderson, and myself. The fifty or so attendees include psychologists, economists, computer security researchers, criminologists, sociologists, political scientists, designers, lawyers, philosophers, anthropologists, geographers, neuroscientists, business school professors, and a smattering of others. It’s not just an interdisciplinary event; most of the people here are individually interdisciplinary.

Our goal is always to maximize discussion and interaction. We do that by putting everyone on panels, and limiting talks to six to eight minutes, with the rest of the time for open discussion. Short talks limit presenters’ ability to get into the boring details of their work, and the interdisciplinary audience discourages jargon.

For the past decade and a half, this workshop has been the most intellectually stimulating two days of my professional year. It influences my thinking in different and sometimes surprising ways­ 00 and has resulted in some unexpected collaborations.

And that’s what’s valuable. One of the most important outcomes of the event is new collaborations. Over the years, we have seen new interdisciplinary research between people who met at the workshop, and ideas and methodologies move from one field into another based on connections made at the workshop. This is why some of us have been coming back every year for over a decade.

This year’s schedule is here. This page lists the participants and includes links to some of their work. As he does every year, Ross Anderson is live blogging the talks. We are back 100% in person after two years of fully remote and one year of hybrid.

Here are my posts on the first, second, third, fourth, fifth, sixth, seventh, eighth, ninth, tenth, eleventh, twelfth, thirteenth, fourteenth, and fifteenth SHB workshops. Follow those links to find summaries, papers, and occasionally audio/video recordings of the sessions. Ross also maintains a good webpage of psychology and security resources.

It’s actually hard to believe that the workshop has been going on for this long, and that it’s still vibrant. We rotate between organizers, so next year is my turn in Cambridge (the Massachusetts one).

The collective thoughts of the interwebz