1.1.1.1 now validates DNSSEC signatures made with ML-DSA-44, a post-quantum signature algorithm standardized by the National Institute of Standards and Technology (NIST). This is a first step toward preparing DNSSEC for a future in which today’s signature algorithms are no longer secure.
Cloudflare plans to achieve full post-quantum security by 2029. Much of the work so far has focused on TLS, but public-key cryptography is used in many other systems, including DNSSEC.
While we began experimenting with post-quantum key agreement in TLS in 2019 and enabled support for all customers in 2022, post-quantum signatures have not yet received comparable testing in DNSSEC. There is also some urgency. Widespread client adoption of post-quantum TLS took years, partly because larger messages exposed assumptions and bugs in existing network software. That experience showed why early large-scale testing matters. We cannot wait until quantum computers become an immediate threat.
The problem is that post-quantum signatures are large. Each ML-DSA-44 signature is 2,420 bytes, exceeding common DNS-over-UDP limits before the response includes anything else. At the same time, zones will need to publish conventional signatures for older resolvers for years, creating a potential downgrade path if not validated correctly. The challenge is carrying these much larger responses reliably, without allowing compatibility with older resolvers to weaken protection for newer ones.
With ML-DSA-44 validation enabled, 1.1.1.1 lets us test both challenges at Internet scale: carrying larger DNS responses and preventing fallback to conventional signatures.
Why post-quantum DNSSEC matters
DNS responses are not authenticated by default. An attacker who can forge a response may be able to redirect users to an address of their choosing. DNSSEC prevents this by signing DNS records. A validating resolver such as 1.1.1.1 follows a chain of signed records from the DNS root to the requested domain, checking that the answer is authentic and has not been modified.
DNSSEC supports multiple signature algorithms, but nearly all of those used today are vulnerable to future quantum computers. RSA and ECDSA rely on mathematical problems that are believed to be infeasible for conventional computers to solve at deployed key sizes. We are preparing for the possibility that in 2030 a sufficiently powerful quantum computer could be built that breaks these keys. An attacker could then recover the corresponding private key and create forged signatures that validators would accept. The attack path is shown below.
Quantum computers capable of carrying out these attacks do not exist today. DNSSEC provides authenticity rather than confidentiality, so it is not subject to “harvest now, decrypt later” attacks. The reason to begin now is that changing DNSSEC requires coordination across authoritative servers, registries, registrars, and validating resolvers. The migration must eventually reach the top of the DNS hierarchy, where a compromised key has the greatest impact. An attacker who recovers a root zone signing key using a quantum computer could forge a validation path to any zone below it: “break once, forge everywhere”. ML-DSA-44 gives that migration a standardized starting point, and supporting it in 1.1.1.1 lets us, and the DNS ecosystem at large, gain operational experience.
Why replacing the algorithm is difficult
DNSSEC was designed to support new algorithms. In principle, supporting ML-DSA-44 means publishing its public key and teaching validators to verify its signatures. In practice, two properties make the transition difficult: the signatures are large, and the old algorithm cannot always be removed safely.
A 2,420-byte signature changes the packet
DNSSEC algorithms commonly used today produce relatively small signatures. ECDSA P-256, for example, produces a 64-byte signature. An ML-DSA-44 signature is 2,420 bytes, almost 38 times larger.
That difference matters because many of the systems that send, carry, and receive DNS messages are sensitive to message size. DNS originally restricted messages sent over UDP to 512 bytes. EDNS(0) later allowed a resolver to advertise the largest UDP response it is willing to accept from a nameserver. Many DNS implementations use a conservative UDP payload limit of 1,232 bytes, chosen to fit within IPv6’s minimum MTU (maximum transmission unit) of 1,280 bytes. More recently, RFC 9715 recommended a maximum of 1,400 bytes for DNS over UDP. An ML-DSA-44 signature exceeds that budget on its own, before accounting for the signed RRset, domain names, DNS headers, and other DNSSEC records. Sending such a response as fragmented UDP is unreliable and should be avoided. Instead, the authoritative server should return a truncated response, prompting the resolver to retry using another transport protocol, usually TCP.
The effect is most visible in DNSKEY responses, which contain the keys a resolver needs to validate the zone. An ML-DSA-44 public key is 1,312 bytes, and the DNSKEY RRset also carries a 2,420-byte signature. ML-DSA-44 cannot fully replace conventional signing algorithms until it is widely supported across the DNS ecosystem, a process likely to take years. Until then, DNSKEY responses may contain both conventional and post-quantum keys and signatures to remain compatible with older validators. Key rollovers can add still more keys, making these responses larger again.
Handling DNS over transports other than UDP is not itself unusual. Cloudflare Radar shows that around 85% of queries to 1.1.1.1 arrive over UDP. The platform behind 1.1.1.1, Big Pineapple, also powers other DNS services, including Gateway DNS. Across all services handled by Big Pineapple, around 60% of queries arrive over UDP. The remaining 40% use transports such as TCP, DNS over TLS (DoT), and DNS over HTTPS (DoH).
Those figures describe how queries reach Cloudflare’s resolver services, not how 1.1.1.1 communicates with authoritative servers. Large ML-DSA-44 responses can still cause additional TCP retries on that side, but handling DNS over transports other than UDP is already a normal part of operating 1.1.1.1 at scale.
Supporting two algorithms introduces a downgrade risk
Replacing an existing DNSSEC algorithm cannot happen all at once. If a zone publishes only ML-DSA-44, resolvers that do not support it cannot validate the zone. The practical migration path is therefore to publish conventional and post-quantum keys and signatures together.
That preserves compatibility, but it does not provide post-quantum security by itself. RFC 6840 specifies that “validators SHOULD accept any single valid path.” This rule lets validators use whichever published algorithm they support.
Once a conventional algorithm such as ECDSA is no longer secure, however, the same behavior creates a downgrade path. An attacker could forge an ECDSA-only answer that a resolver accepts despite supporting ML-DSA-44, as illustrated below.
Preventing this downgrade requires an authenticated signal that a zone should be validated with ML-DSA-44. 1.1.1.1 uses DS records published by the parent zone for this purpose. If the authenticated DS RRset contains a record for a supported post-quantum algorithm, the signal is present.
1.1.1.1 then deliberately applies a more restrictive local validation policy. It requires at least one valid post-quantum validation path; a conventional path is no longer sufficient. If no ML-DSA-44 path validates, validation fails. This is not (yet) normal DNSSEC validation behavior, but RFC 4035 allows local resolver policy to determine whether additional signatures must be checked and how conflicting results are handled.
Conventional signatures can remain available for older resolvers without allowing post-quantum-capable resolvers to fall back to them. The downgrade signal is only post-quantum secure if ML-DSA-44 deployment and downgrade protection extend from the trust anchor through every delegation. Rotating the zone key more frequently does not solve the problem: an attacker can target a vulnerable key anywhere higher in the chain and forge every delegation below it.
The road to post-quantum DNSSEC
Adding a post-quantum algorithm to DNSSEC requires more than standardizing the cryptography. It needs implementations in cryptographic libraries, an IANA-assigned DNSSEC algorithm number, support from authoritative servers and validating resolvers, and adoption throughout the DNS delegation chain. ML-DSA-44 now has the initial prerequisites for deployment. NIST has standardized it, and common cryptographic libraries implement it. Its use in DNSSEC is described in the ML-DSA for DNSSEC Internet-Draft, and IANA recently assigned it DNSSEC algorithm number 18.
Adding ML-DSA-44 validation to resolvers is one of the first deployment steps, but it does not create a complete post-quantum chain of trust. Authoritative servers must sign zones with ML-DSA-44, registrars must accept and submit the corresponding DS records, and registries must publish them in parent zones.
This adoption must extend through every parent zone to the DNS root. The root must adopt ML-DSA-44, and its post-quantum key must become a trust anchor for validating resolvers. Any level without post-quantum protection remains a downgrade point.
There is little value in signing a zone with ML-DSA-44 if no resolver validates its signatures. Enabling ML-DSA-44 validation by default on 1.1.1.1 is therefore an important early step. It lets us measure the operational cost of signature verification, additional bandwidth, and increased TCP use between resolvers and authoritative servers.
As with previous migrations, we will also test real-world deployability using background probes on a small fraction of Cloudflare Challenge Pages. These probes will test whether clients can resolve and reach an ML-DSA-44-signed test domain across real networks. We invite other DNS operators and implementers to begin testing ML-DSA-44 at scale. Together, these measurements will show what adjustments are needed as adoption grows.
What this means for you
If you use 1.1.1.1, you do not need to change anything. ML-DSA-44 validation happens automatically when a zone publishes the necessary DNSSEC records, while existing DNSSEC zones continue to validate as before.
This work covers the resolver side of DNS. Our next step is adding ML-DSA-44 signing support to Cloudflare Authoritative DNS and corresponding DS record support to Cloudflare Registrar, which will be available to all customers for free. That will let us test the complete path, from generating signatures and publishing DNSKEY records to transporting and validating them through 1.1.1.1.
Want to see post-quantum DNSSEC in action… all 2,420 bytes of it? Query our dnstest.dev zone using 1.1.1.1:
Post-quantum cryptography is now one pip-install away for the entire Python ecosystem. With funding from the Sovereign Tech Agency, we implemented support for ML-KEM, the NIST-standard key-establishment primitive, and ML-DSA, the NIST-standard digital-signature primitive, in pyca/cryptography.
Remember, the reason to do this now is because there’s no emergency. And because you will make your systems crypto agile, which is always a good idea.
Cloudflare's Authenticated Origin Pulls and Custom Origin Trust Store now support post-quantum authentication.
Here we’ll explain how you can configure fully post-quantum secure mutually authenticated TLS connections to your origin server, dive into the engineering details of how we built it, make a shameful confession, and finally explain how this work fits into our overall post-quantum migration roadmap.
Reaching a major milestone
Our focus for the past several years has been in deploying post-quantum encryption to protect against harvest-now/decrypt-later attacks, where an attacker quietly stockpiles your encrypted data with the hope of decrypting it in the future with a quantum computer.
However, recent breakthroughs in quantum computing and cryptanalysis pulled the timelines for upgrading to post-quantum cryptography forward acrossindustry and government and have caused us to shift our attention to deploying post-quantum authentication, to protect against attackers who will soon be able to use quantum computers to break classical credentials and carry out impersonation attacks.
In a previous post, we announced that Cloudflare is targeting 2029 for full post-quantum security, and laid out several milestones to hit along the way. We have reached the first of those milestones: our Authenticated Origin Pulls and Custom Origin Trust Store products now support post-quantum (PQ) authentication via Module-Lattice-Based Digital Signature Algorithm (ML-DSA) signatures to protect connections between Cloudflare and customer origin servers.
The origin connection is different
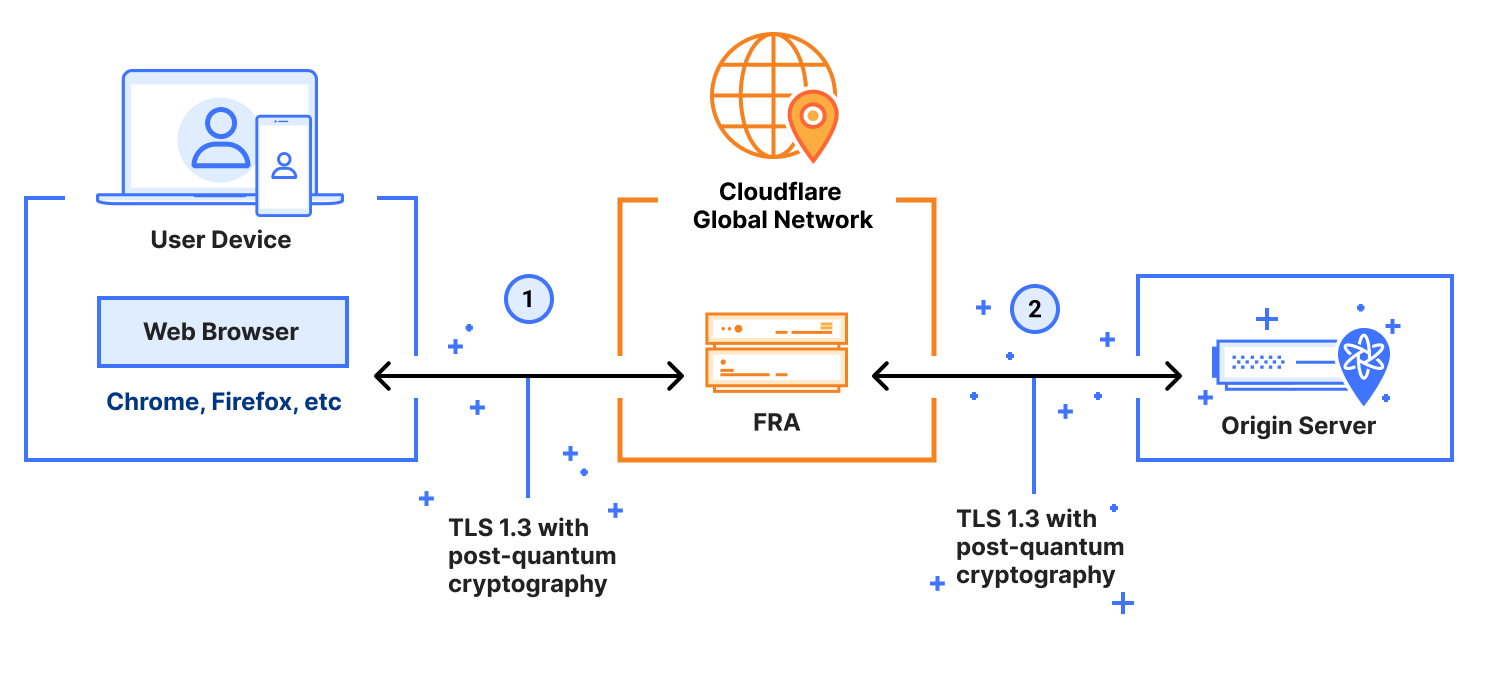
When a client visits a website proxied by Cloudflare, there are typically two connections involved. The first connection is from the visitor (e.g., a browser) to Cloudflare. If the request can be served from Cloudflare’s cache or triggers any blocking rules, Cloudflare might respond directly. Otherwise, Cloudflare establishes a second connection to the customer’s origin server to fetch the requested content, so it can respond to the original request.
Protecting sensitive visitor data requires both of these connections to be secure against quantum attacks. We enabled post-quantum encryption support for both the visitor-to-Cloudflare (Connection 1) and Cloudflare-to-origin (Connection 2) connections in 2022 and 2023, respectively, and already see significant usage.
We are actively working on completing the picture with post-quantum authentication. For the visitor-to-Cloudflare connection, we are collaborating with Google and others at the Internet Engineering Task Force (IETF) to develop and experiment with Merkle Tree Certificates (MTC), a design for fast, post-quantum certificates for the web, with initial deployments targeting 2027. The topic of this post, however, is the Cloudflare-to-origin connection, where the requirements for authentication differ from that of the visitor-to-Cloudflare connection in several important ways.
For this connection, Cloudflare is the client. This gives us the control to employ techniques such as connection pooling to fan in requests from all over our network to a smaller set of connections to origin servers, amortizing the overhead of connection setup over many requests. This makes the cost of “drop-in” post-quantum signatures more palatable, and the performance benefits of MTC less necessary.
And with a pre-existing trust relationship between Cloudflare and customers (i.e., a Cloudflare account), we need not tie ourselves to the constraints and timelines of the public key infrastructure (PKI) for the public Internet (WebPKI) and can instead use custom PKIs tailored to the use case, without overhead from intermediate certificates and Certificate Transparency that may not be applicable. Solutions like Cloudflare Tunnel can also be used to protect the Cloudflare-to-origin connection without upgrading legacy origin systems, by forwarding traffic over a tunnel secured with post-quantum encryption (and post-quantum authentication in the works).
All this to say, the unique requirements of the Cloudflare-to-origin connection have allowed us to deploy post-quantum authentication via ML-DSA authentication ahead of support landing in the WebPKI for the public Internet. (For customers who stick with the WebPKI, don’t worry: we’ll add MTC support on the Cloudflare-to-origin connection in the future.)
So how do you turn this on? Let’s dive into the configuration.
Configuring fully PQ-secure origin connections
We have added ML-DSA support (for all FIPS 204 parameter sets: ML-DSA-44, ML-DSA-65, and ML-DSA-87) to the Custom Origin Trust Store and Authenticated Origin Pulls products. ML-DSA-44 is our recommendation for most applications as it is the most performant option and attains a comfortable NIST category 2 security strength.
Custom Origin Trust Store
When Cloudflare makes a connection to a customer origin server configured with Full (strict) SSL mode, we authenticate the origin certificate against a default trust store consisting of all commonly trusted Certificate Authorities (CAs) as well as Cloudflare’s origin CA. The Custom Origin Trust Store (COTS) product (which requires Advanced Certificate Manager to be enabled) allows customers to replace this default trust store with a set of CAs they control. COTS now allows customers to upload ML-DSA CAs, such that Cloudflare will trust any origin server certificate chaining to that CA when connecting to the origin.
Authenticated Origin Pulls
To limit abuse and resource consumption on their origin servers, customers may want to only serve requests coming from Cloudflare’s servers. Authenticated Origin Pulls (AOP) can be used to configure Cloudflare to present a client certificate to the origin server in order to establish a mutual TLS (mTLS) connection, in which communication between the parties is bidirectionally secure and trusted. AOP is available for free on all Cloudflare plan levels.
AOP supports three configuration levels: global, per-zone, and per-hostname. The per-zone and per-hostname configuration levels now allow customers to upload ML-DSA certificates and private keys (in the FIPS 204 seed format), so that Cloudflare’s TLS client will present this certificate to authenticate itself when connecting to the origin server. (Don’t worry, we haven’t forgotten about the global configuration level — it just happens to be a more involved change that will be prioritized at a later date.)
Avoiding downgrades
Adding post-quantum encryption and authentication support to both the authenticating and verifying parties is necessary but not sufficient for full post-quantum security. The pesky issue of downgrades remains. If the verifying party supports any quantum-vulnerable authentication mechanisms, they remain open to attack from an on-path attacker capable of forging classical credentials.
The fix: the verifying party must remove trust in quantum-vulnerable authentication mechanisms. (This is more nuanced in complex PKIs. For example, see the Chromium Security team’s four-stage plan for transitioning the Web.) See the configuration guide for AOP and COTS for details on how to ensure your origin is secure against downgrade attacks.
Quick start
The walkthrough below shows how to generate an ML-DSA certificate chain and configure both products via the Cloudflare API. For dashboard instructions and additional context, refer to the developer docs.
1. Generate certificates
You will need OpenSSL 3.5.0 or later. The private key must be generated in the FIPS 204 seed-only encoding, which is the only format Cloudflare currently accepts on upload.
Origin server certificate chain for COTS:
Cloudflare client certificate chain for AOP:
2. Upload the origin CA to Custom Origin Trust Store
Uploading a COTS CA replaces the default publicly-trusted CAs for the zone. Make sure you only upload post-quantum CAs if you want to avoid downgrade attacks.
3. Upload the client certificate for Authenticated Origin Pulls
The example below uses zone-level AOP. If you prefer per-hostname AOP, use the /origin_tls_client_auth/hostnames/certificates endpoint instead.
4. Set your SSL/TLS mode to Full (strict)
Custom Origin Trust Store is only active when your zone is using Full (strict) mode. If you are using AOP without COTS, Full or higher is sufficient.
5. Configure your origin server (on NGINX)
If you are using COTS (your origin presents the ML-DSA server certificate):
If you are using AOP (your origin verifies Cloudflare's client certificate):
If you are using both together (recommended for full post-quantum mutual TLS):
6. Verify the post-quantum handshake
The TLS handshake between Cloudflare and your origin happens behind the scenes, so you cannot observe it directly by connecting to your proxied hostname from the outside. Instead, verify each side separately.
Verify COTS (origin presents an ML-DSA certificate):
If your origin IP is directly reachable (for example, during testing before enabling the Cloudflare proxy), connect to the origin IP directly and validate the certificate:
Look for Signature type: mldsa44 in the output.
If your origin is firewalled to only accept Cloudflare IPs, check your origin server's TLS logs or use a packet capture tool such as ssldump or tcpdump on the origin to confirm that Cloudflare negotiated TLS 1.3 with the ML-DSA certificate.
Verify AOP (Cloudflare presents a client certificate):
Confirm that direct connections to the origin (without a valid client certificate) are rejected:
With ssl_verify_client on enforced, this should fail with an SSL alert.
Verify the full Cloudflare-to-origin path:
Because the mTLS handshake happens server-to-server, the most reliable way to confirm that Cloudflare is presenting the ML-DSA client certificate is to inspect your origin server logs. For example, in NGINX you can log the client certificate serial number or subject:
After sending a request through Cloudflare, check the log. You should see the serial number of the aop-client.crt certificate you uploaded.
For the key agreement, ensure that your origin's TLS library supports X25519MLKEM768 and that it is preferred in your configuration. The post-quantum key agreement will be visible in origin server logs or packet captures as the negotiated group.
The boring details
Implementing this feature involved two primary systems: our control plane service that allows customers to manage their TLS settings and upload certificates, and the data plane service responsible for establishing TLS connections to origin servers based on customer configurations.
Control plane
As with many other services that power Cloudflare’s APIs and Dashboard, the service that powers the configuration for Cloudflare’s SSL/TLS products runs in a highly available setup across a set of critical data centers. The service is responsible for handling SSL/TLS settings updates and pushing them out to our globally-distributed key-value store so that they are available to data plane services when handling live requests.
Enabling ML-DSA support for AOP and COTS required updating this service to support parsing and validating ML-DSA certificates. This sounds simple on paper, but there’s a catch: the service is written in Go, but Go’s standard X.509 and TLS libraries did not yet support ML-DSA. We instead implemented the necessary functionality in Cloudflare’s CIRCLlibrary to patch in support. This was a relatively simple change, but repeating this for every service that needs post-quantum authentication support would be a major chore.
Fortunately, Go 1.27 (expected August 2026) will include native ML-DSA support, and will allow us to drop the CIRCL dependency. Other Go-based services will then be able to seamlessly pull in ML-DSA support with a simple version update.
Data plane
With the control plane changes in place, customers could then upload ML-DSA certificates for the AOP and COTS products. The next step was to update our data plane service responsible for interacting with customer origins to actually use those certificates.
We have talked in previous blog posts about our open-source proxy framework Pingora and specifically how we have a Pingora-based service that handles all the connections to those origins. That service is unimaginatively named Pingora Origin, and it is responsible for ensuring millions of requests per second worth of origin-bound requests make it safely and securely to their final destination.
The task of ensuring the request’s security typically falls to the TLS provider, and it may surprise you to know that post-quantum security (or in this case authenticity) is no different. It also might come as a letdown that defending against quantum attacks does not require exotic states of matter with lasers and superconducting Josephson junctions; all you need is an update to BoringSSL. Now, BoringSSL lives up to its name: over the past several years, there have been no CVEs or major changes. In fact, we relied on that stability so heavily that we have an admission to make: we snoozed Pingora Origin’s update to BoringSSL for four years, instead maintaining an internal fork to patch in additional functionality as needed. That has worked well, but when post-quantum authentication support landed in BoringSSL in April 2026, we decided that this update was worth the inconvenience.
This is where we wish we could say, “This update went perfectly. No notes!” but naturally there were some hiccups. Within the four years’ worth of code changes was this commit that enables enforcement of rules related to KeyUsage in TLS certificates. This change is in line with the specifications, but as we have seen before, the Internet is not known for being RFC compliant. The result was that even after testing the changes for weeks and a very slow release rollout looking for just this sort of regression, a small number of customers’ certificates were deemed invalid after the change, leading to an incident on June 10, 2026. We quickly rolled back the change and after a patch to retain support for RSA certificates with technically invalid KeyUsage, fully post-quantum secure TLS to origins is now live and ready to use.
We are only getting started
ML-DSA support is increasingly ubiquitous across TLS libraries, and routine software updates will bring post-quantum authentication support to many applications. (Please keep your libraries updated!) The highly-anticipated Go 1.27 (August 2026) will come with native ML-DSA support, allowing Go-based services to add post-quantum authentication with a simple version update.
As these changes propagate across the ecosystem, we will be upgrading our systems as well. See PQC in Cloudflare Products for an up-to-date tracker of post-quantum encryption and authentication support in Cloudflare products and services.
RSA and ECC, cryptographic algorithms that we’ve all relied on for decades, are vulnerable to the attack of sufficiently advanced quantum computers. Such quantum computers do not exist yet, but they seem to be coming sooner than expected. Luckily, the solution is already available: migrate to ML-KEM encryption and ML-DSA signatures, which are designed to be resistant to quantum attack. They were standardized in 2024 by the U.S. National Institute of Standards and Technology (NIST) after an eight-year open international competition.
The migration to post-quantum cryptography is in full swing now. At the time of writing, the majority of traffic handled by Cloudflare is already using ML-KEM encryption, and is thus secured against the threat to data posed by harvest-now-decrypt-later attacks. But encryption is only one part of the equation: to be fully secure against quantum computers capable of breaking classical cryptography, we aim to deploy post-quantum signatures to protect authentication systems from unauthorized access. We are targeting 2029 for Cloudflare to be fully post-quantum secure.
ML-DSA, the best all-around post-quantum signature scheme standardized today, has its downsides: it’s much larger on the wire, and many tricks we were able to perform with RSA and ECC simply cannot be done with ML-DSA. There are better post-quantum signature schemes on the horizon: last month, NIST announced that it is advancing nine post-quantum signature schemes to the third round of the “signatures on-ramp”. And a draft standard for FN-DSA (née Falcon), which was picked from the previous competition, is expected imminently.
We have been very interested in advances in post-quantum signature algorithms, and wrote about the progress in 2021, 2022, 2024, and 2025. In this blog post we’ll treat you to the latest developments in great detail.
But first we have to deal with the elephant in the room: These new signature algorithms will not be ready in time for the PQ transition — not even close, as we will see later on. The problem is arriving too soon for us to wait. ML-DSA is available today, and it will have to do for the first migration. As Eric Rescorla wrote in 2024:
You go to war with the algorithms you have, not the ones you wish you had.
Nonetheless, the search for better post-quantum signature algorithms is crucial for several reasons, and we firmly believe it is still the best use of NIST’s limited resources.
Let’s have a look at the signature algorithms in detail. After that we’ll look at the timeline for their availability, and the reasons why we still need them.
The signature algorithms
In the table below, we compare the candidate signature algorithms that progressed to the third round (marked by 🤔), with classical algorithms vulnerable to quantum attack (marked by ❌), and the post-quantum algorithms that are already standardized ( ✅) or soon will be (📝). Each candidate proposes several variants. We list the most relevant variants to TLS, the protocol used to secure connections on the Internet. To explore all variants, check out Thom Wiggers’ signatures zoo.
Sizes (bytes)
CPU time (lower is better)
Family
Namevariant
A
Public key
Signature
Signing
Verification
Elliptic curves
Ed25519
❌
32
64
0.15
1.3
Factoring
RSA 2048
❌
272
256
80
0.4
Lattices
ML-DSA 44
✅
1,312
2,420
1 (baseline)
1 (baseline)
Symmetric
SLH-DSA 128s
✅
32
7,856
14,000
40
SLH-DSA 128f
✅
32
17,088
720
110
SLH-DSA 128-24
📝
32
3,856
7,000,000 ⚠️
4
LMS M24_H20_W8
✅
48
1,112
2.9⚠️
8.4
Lattices
FN-DSA 512
📝
897
666
3 ⚠️
0.7
Lattices
HAWK 512
🤔
1,024
555
0.25
1.2
Proof of knowledge
MQOM L1-gf16-fast-5r
🤔
60
3,280
8
20
SDitH SDitH2-L1-gf2-fast
🤔
70
4,484
15
40
FAEST EM-128f
🤔
32
5,060
4.2
9
Isogeny
SQIsign I
🤔
65
148
300 ⚠️
50
Multivariate
MAYO one
🤔
1,420
454
2.1
0.4
MAYO two
🤔
4,912
186
1.1
0.8
QR-UOV I-(127 156 54 3)
🤔
24,225
200
9.3
20
SNOVA (24,5,4)
🤔
1,016
248
1.2
1.7
SNOVA (25,8,3)
🤔
2,320
165
1
1.5
SNOVA (37,17,2)
🤔
9,842
124
0.8
1.3
UOV Is-pkc
🤔
66,576
96
0.3
2.4
UOV Ip-pkc
🤔
43,576
128
0.3
2
A few more remarks on this table: Most candidates have multiple variants in every security level. We show the most relevant variants for TLS at the 128-bit security level, the gold standard for security. CPU times are taken from the signatures zoo in June 2026, which collected them from the round two submission documents and later advances. Candidates are allowed to make changes for the third round, which will influence these numbers. Some will improve (both in compute and size), whereas others will regress to counter new attacks. Check out the zoo for the latest numbers. We marked FN-DSA and SQIsign signing with a ⚠️️, as both are hard to implement in a fast and timing side-channel secure manner. LMS signing has a ⚠️, as secure LMS signing requires keeping state across signatures, and the listed signing time assumes a 32MB cache. The 128-24 variant of SLH-DSA is marked with a ⚠️️ as it’s meant to create fewer than 224 signatures.
No “all-star” algorithm
One thing that stands out immediately is that the quantum-vulnerable elliptic curves signature algorithm Ed25519 is by far the best all-around choice (ignoring its quantum vulnerability): it has the best numbers in almost every single metric, including public key size, signature size, and signing time. It’s only beaten on verification time, but it’s more than fast enough for the vast majority of applications.
This is quite different than the roster of post-quantum algorithms. Instead of a single “all-star” algorithm, we have roughly two categories of schemes: the “specialists” that approach our trusty elliptic curve signatures on some metrics, but are problematic on others, which make them great in the right deployment scenario. Then there are the “generalists”, such as ML-DSA, which don’t perform as well as elliptic curves on all metrics, but so far as downsides go, are pretty balanced.
Specialists
Let’s start with the specialists.
SQIsign: small signatures / slow signing
If you just look at the bytes on the wire, then SQIsign looks like an almost perfect drop-in replacement for elliptic curve cryptography. With signatures of 148 bytes and public keys of 65 bytes, it beats RSA-2048. Unfortunately there is no free lunch: SQIsign has three weak points. First, it’s the most complex algorithm on the docket. Secondly, its signature creation and verification is quite slow. Finally, it’s difficult to implement signature creation in a timing side-channel secure way and doing so comes with a performance penalty to boot.
That doesn’t sound great so far, but it was much worse: when we had a look back in 2024, there was not yet any timing side-channel secure implementation and signature verification was 20x slower. Furthermore there has been welcome progress on simplifying the scheme.
Despite these dramatic improvements, it is unlikely (side-channel secure) signing will be fast enough in the foreseeable future to be used in typical online cases such as the TLS handshake. However, for offline cases, such as CA signatures or DNSSEC, where it’s the verification time that’s more important than the signing time, SQIsign might have an application.
But the topic we should really discuss is security. SQIsign is based on isogenies. Rather famously, SIKE, another algorithm based on isogenies, got broken badly in a late stage of the first NIST PQC competition that standardized ML-DSA. SIKE is often brought up as a cautionary example showing that post-quantum cryptography could break suddenly. This requires some nuance. First, there were already concerns about SIKE’s security, and in particular the torsion points that led to the break. Because of these concerns, SIKE was not selected for standardization, but deferred to an additional round of evaluation before it was broken. (Indeed, this is an example of the NIST process working well.) SQIsign doesn’t use torsion points, and there is no similar concern as there was for SIKE.
One other notable security property is that the best known attacks on SQIsign are generic brute force, just like with classical attacks on well-selected elliptic curves. This is quite different from RSA, lattices, and multivariate where the attack algorithms have been slowly improving, pushing the parameters towards bigger signatures. Nonetheless, the mathematics behind isogenies is very rich, and compared to the other algorithms, there is a lot of mathematical attack surface. Still, its security seems more sound than the structured multivariate algorithms we’ll discuss later.
SQIsign is an algorithm with tremendous potential. It’d be a shame to standardize it too early. To the authors, we’d like to share the following wishlist:
Ideally verification time is decreased even further, even if this trades off against signing time and signature size: SQIsign signatures are already small enough, and offline signing time has some slack anyway.
The timing side-channel secure implementation should be the default, especially if signing time is decreased further, which would tempt some online signing applications.
But above all, our wish is for SQIsign to be simplified.
UOV: tiny signatures / huge public keys
UOV (unbalanced oil and vinegar) is a classic multivariate signature algorithm originally proposed in 1999. It has tiny signatures: only 96 bytes. The trade-off? A huge public key: 66kB. That wouldn’t help for a TLS server certificate, whose public key is transmitted over the wire when setting up a connection, but it would be a help for cases where the public key is predistributed.
Let’s take the WebPKI as an example. A typical browser trusts about a hundred root certificates and 30 certificate transparency logs, whose public keys would add up to about 8MB when using UOV.
The public keys and signatures in a typical TLS connection.
Since the root certificate is transmitted to clients out of band, one idea is to use a UOV signature there. But this is not a slam dunk; because of its size, a UOV root certificate would be impractical to be cross-signed where the root is used as an intermediate. At the same time, cross signs and intermediates become less attractive anyway with any larger post-quantum signatures. This encourages more root certificates to be included directly with clients. This would again favor UOV, but to a point: if the number of root certificates grows above a thousand, we’d be dealing with more than 66MB of key material, which would make up a substantial portion of the browsers’ download size (e.g., 90MB for Firefox 151.)
Multivariate security
What about the security? Over the years, many variants of UOV have been proposed that use some extra mathematical structure to reduce the size of the public key. These structured multivariate schemes have had a spotty track record with schemes such as Rainbow and GeMMS being broken quite badly. It is important to distinguish these from UOV itself, whose security track record is much better, but not perfect.
As with many cryptographic schemes, there were growing pains in the early years, as basic attacks and parametrization pitfalls were discovered. In fact, the “U” in UOV is a remnant of that: it stands for unbalanced, which is a fix to a parameter-setting mistake in the 1997 oil-and-vinegar scheme on which UOV is based: the original scheme had an equal number of oil and vinegar variables in the quadratic system of equations used as the public key, which turns out to allow for an attack. In case you’re curious about the colorful name: the system of equations contains vinegar x vinegar and oil x vinegar, but no oil x oil terms. It’s like vinaigrette with small separate oil droplets. Back to the history: from 2005 to 2020 was a quiet period for multivariate signatures: understanding of UOV grew, but there weren’t any new attacks on typical parameters.
This changed in 2020 with the discovery of the intersection attack which built on the ideas of the original attack on balanced oil-and-vinegar. The intersection attack removes about 30 bits of security from a then-proposed 128-bit parameter set. A considerable blow, but not fatal: slightly adjusting parameters mitigates the attack completely, with minor increase in key and signature size.
A bigger shock was the 2025 publication of the idea to use wedges to attack multivariate schemes. The initial impact on UOV was minor: only a few bits (again at the 128-bit security level.) The worry was that this idea came out of left field, and it wasn’t clear how far the approach could be taken. That concern was partly justified: the wedges idea was very fruitful and several subsequent attacks have been built on it, reducing security by about 15 bits. However, it also became clear that the wedges attack and generalizations can be seen as a special case of an intersection attack over truncated rings — thus much more familiar than we thought. Again, these attacks can be mitigated with only minor increases in key and signature size.
What to make of all of this? Such a history of attacks is not uncommon: over the last 25 years lattices have seen larger reductions in security, although this has calmed down over the recent years. Notwithstanding, lattice-based cryptography deployed in production today uses conservative parameter sets well above 128-bits to hedge against future cryptanalysis. We’d want to do the same with UOV. Signature size only grows linearly with the security level, costing just 260 bytes even at the 256-bit security level. Unfortunately, the public key size is cubic in security level: 446kB for 256-bit. Conveniently, UOV (as most multivariate schemes) has a lot of flexibility in picking parameter sets at various intermediate security levels.
UOV is a foundational scheme with narrow but real use cases. Going forward, we’d like to see a parameter set with a bit of margin above 128 bits, say 160 bits, to hedge against future cryptanalytic improvements.
QR-UOV: small signatures / large public keys
Like SNOVA and MAYO which we’ll discuss later on, QR-UOV is a structured multivariate scheme: it’s a variant of UOV that adds more structure to the public key to reduce its size. The gains are modest: at best we’re looking at 12kB public keys, but signature verification is impractically slow for that particular parameter set. The more realistic parameter sets start at 24kB public keys.
With respect to security, QR-UOV is the only multivariate scheme that did not have to adjust its original (round one) parameters in response to new attacks. This is somewhat surprising as any attack on UOV can also be applied to QR-UOV. The explanation is that the attacks do apply, but the natural parameters for QR-UOV happen to make them ineffective. On the other hand, there were already several attacks known that use the specific extra structure that QR-UOV adds: indeed, for some of the parameter sets, the structure-specific attacks are the best attacks. This should be contrasted with MAYO, where there is no known attack against the extra structure MAYO adds. (We’ll get back to MAYO and SNOVA later in this post.)
Compared to last round, QR-UOV signing and verification time improved significantly, but it is still comparatively slow. All in all, QR-UOV is a hard sell: it adds exploitable structure to UOV without pushing key sizes down to general-purpose sizes.
Hash-based signatures
Stateful hash-based signatures
The very first standardized post-quantum signature algorithms are the stateful hash-based LMS, HSS and XMSS(MT). They have very small public keys, and for many parameter sets the signatures are much smaller than those of ML-DSA-44. To boot, their security is based on that of hashes, which are well-understood and already a cornerstone of cryptography. That makes hash-based signature algorithms a very conservative choice, and there is no need to hedge with higher security levels.
So, what’s the catch?
There are two. The big one is keeping the eponymous state. These stateful hash-based signature schemes are built out of one-time-signature keys which are collected into Merkle trees. The signer has to keep track of which one-time-signature keys have been used, which can be as simple as just a counter. If the signer mucks it up, though, and accidentally uses the same one-time-signature key twice on a different message, then anyone can likely use those two signatures to create their own signature on any message. You have to keep a lot in mind to keep the state correctly. Some considerations: you want to make sure that updates are written to storage before handing out the signature; you don’t want the old state to be restored from a backup; and you can’t export/import a private key from one place to another without agreeing on how to split or keep the state. The state is, as Adam Langley pointed out several years ago, a huge foot-cannon.
Another downside is that the most competitive parameter sets can only create a modest number of signatures. The 1,112 byte signatures (as listed in the table above) can only be used to create about a million signatures. You can explore the trade-offs with this calculator.
Together this leaves a very small niche for stateful hash-based signatures: signers have to be able to keep state; signature size has to be a real concern; and signers have to be OK with a hard limit on the number of signatures.
SLH-DSA: conservative security / large and slow
SLH-DSA is a hash-based signature that doesn’t have the low signature limit and avoids the problem of keeping the state. The basic idea is to make the number of one-time-signature keys so large that you can pick one at random without having to worry about using the same one twice, since the chance of picking the same one twice is diminishingly small. SLH-DSA is a bit more efficient than that, by replacing the one-time-signature key as a building block with a few-time-signature key, where security degrades gracefully if keys are occasionally reused. It still comes at a cost. SLH-DSA has two variants, one that optimizes for small signature size, and one that optimizes for fast signing. The size-optimized one is not small at all at 8kB, and the signing-optimized one is even slower than SQIsign.
Fewer signature variants of SLH-DSA
NIST has proposed to standardize an additional parameter set for SLH-DSA with much smaller signatures, but that can only be used to create about 16 million signatures before security reduces. At 3.8kB the signatures are still larger than those of ML-DSA-44, but the combined public key and signature size is very close. The parameter set was chosen to make signature verification fast at the cost of signing time. The signing time is very bad indeed.
Use cases
So why ever use SLH-DSA? The selling point is the conservative security. For a long-term trusted key that is hard to replace, it could make sense if the application can stomach the large signature and slow verification of the standardized variants or the slow signing time of the newly proposed one. There are two more caveats to add. First, it’s better to set things up so that key algorithms are not burned-in and can be replaced after the fact. And secondly, in most cases systems (such as secure connections with TLS) do not just depend on signatures, but also on key agreement. There is no hash-based key agreement mechanism, so we end up needing to trust something less conservative, like lattices, anyway.
FN-DSA: small key and signatures / subtle signing
Comparing the numbers, FN-DSA-512 (née Falcon) looks much better than ML-DSA-44 on almost every metric: faster verification, smaller public key, and much smaller signatures at 666 bytes. Signing is three times slower, but it’s still 25x faster than RSA-2048. To boot it’s already picked to become FIPS 206. So why don’t we consider FN-DSA to be a general-purpose algorithm?
It’s because it’s difficult to implement FN-DSA signing securely. The most well-known sharp edge of FN-DSA is that it is most naturally and efficiently implemented using hardware-accelerated floating-point arithmetic. This is a first for a cryptographic standard. One big challenge with it is that we have little experience implementing fast floating-point arithmetic in a side-channel safe way. What we know so far is that it’s subtle and not very robust: a safe implementation of FN-DSA signing using the Floating-Point Unit (FPU) for one processor might not be safe for another. Instead of relying on the FPU, the floating point operations can be emulated. This is easier to get right, but about 20 times slower, making it about as slow as RSA-2048. There has been some welcome progress recently to implement FN-DSA signing safely using fixed-point arithmetic, which is much faster than the floating-point emulation. So just use that and FN-DSA is good to go? This presumes a level of awareness that might not be warranted. Anecdotally at conferences, every time we saw a presenter compare post-quantum signature algorithms including FN-DSA in benchmarks, they couldn’t answer whether floating-point emulation was used.
Another consequence of using floating points is that it’s difficult to make test vectors for signing. Just one example of this is that the outcome of a+(b+c) and (a+b)+c are only guaranteed to be close, but not the same. That means that to have useful test vectors, the FN-DSA specification would need to be very precise on the order of floating-point operations. Another example is a*b+c, which can be computed in two steps (multiply and then add), or at once using fused-multiply-add (FMA). The latter is faster, but again gives a slightly different answer as rounding happens only once. Not all processors support FMA, but for those that do, compilers typically automatically use FMA for the performance boost. There are also mathematical optimizations that cause trouble. For instance, the reference implementation computes a value (norm) in a faster roundabout way using Parseval’s theorem. Mathematically the answer is exactly the same, but as floating-points are only an approximation, the resulting value is ever so slightly different. Similarly, the safe fixed-point arithmetic implementation gives slightly different results.
Why is this a problem? It is because it is still the humble test vector that catches most implementation bugs in practice. Other more refined methods like formal verification will certainly catch more, but test vectors are hard to beat in simplicity.
Another surprising sharp edge from not having a fixed implementation is the following. From two deterministic signatures created by slightly different implementations from the same private key, one can derive parts of that private key. FN-DSA does not use deterministic signatures, instead adding a randomizer to thwart this. There is a tension with testing: you need a deterministic interface to test signing, but you don’t want that to be used to create actual signatures.
How to deal with the wiggle room in the FN-DSA specification will undoubtedly be a point of discussion. The discrepancy between the implementations might actually have a silver lining: NIST could decide to generate the test vectors (CAVP) from the fixed-point arithmetic implementation. That the more risky floating-point implementation wouldn’t pass the test vectors would be a feature, not a bug, as it would steer implementations towards the safer fixed-point version!
You can read about a few other interesting sharp edges in this blog post. Stepping back from the specifics, the main point is that FN-DSA is a complicated scheme. It’s not a surprise that it took NIST a couple of years (not counting the current limbo) just to write the draft standard. It’ll take longer than usual for the final standard to come out and for cryptographic libraries to add support. FN-DSA is farther away than it seems. We’ll compare timelines later in this blog post.
If the numbers are still very tempting, there is one last thing you should be aware of: FN-DSA-512 is parametrized for 128-bit security compared to ML-DSA-44’s generous 160 bits. If lattice cryptanalysis improves, there is no middle security level: the next step-up is all the way to FN-DSA-1024 at 256 bits. FN-DSA-1024 has double the key and signature sizes and signing and verifying times of FN-DSA-512. An FN-DSA-1024 signature is still half the size of that of ML-DSA-44, but the public key+signature only differs about 20%.
To close the discussion of FN-DSA, it is good to emphasize that all difficulties with FN-DSA are on the signing side: the verification of an FN-DSA signature is very straightforward.
General-purpose algorithms
Now let’s turn to the algorithms that are meant to be general-purpose replacements for ML-DSA.
HAWK
HAWK is a curious case. In many aspects it’s similar to FN-DSA: a structured lattice hash-then-sign scheme with similar sizes for signatures and public keys with a missing middle security level. The main benefit of HAWK over FN-DSA is that signing is very fast and doesn’t use floating-point arithmetic, although it’s not a simple algorithm either. This comes with a trade-off: HAWK is based on and introduces a new security assumption, the lattice isomorphism problem (LIP). In 2024, two years after the introduction of HAWK, it was discovered that this problem is easy to solve in the special case of totally real number fields, which aren’t used in HAWK or any other cryptography. In 2025, this attack was extended to a broader class of number fields. This hasn’t yet applied to HAWK, but it’s getting closer. A new paper published in June 2026 suggests there is a way to extend the attack to HAWK. An error has been found in the paper, although it’s yet unclear how fundamental it is to the approach. Regardless, the trajectory is concerning.
Even ignoring the potential attacks, HAWK faces some headwinds: its additional security assumption prevents it from displacing FN-DSA, but its practical benefits (especially considering the lack of middle security level) fall short of that of the structured multivariate candidates. It also doesn’t increase diversity in security assumptions, an outcome that NIST is hoping for.
Proof-of-knowledge schemes
FAEST, MQOM, and SDitH all share a similar overall structure. Their public keys are instances of some hard problem and their secret keys are the solutions.
A FAEST public key is the AES-encryption of a known plaintext under a secret key.
MQOM gets its name from the Multivariate Quadratic problem, which is closely related to (but more conservative than) the cryptographic assumptions underlying the multivariate schemes. The public key is a system of quadratic equations, and the secret key is a solution to that system of equations.
SDitH is based on the hardness of the Syndrome Decoding problem for random linear codes. This problem is related to the code-based schemes submitted to the original NIST competition, but these were eliminated in the third round.
In all cases, a signature is a zero-knowledge proof that the signer knows the solution of that hard problem, while at the same time (almost as an afterthought) acknowledging the message-to-be-signed as part of the proof.
Many signature schemes are zero-knowledge proofs like this behind the scenes, notably ML-DSA, SQIsign, and Ed25519. Why don’t we group those with proof of knowledge schemes too?
The difference is generalizability: the zero-knowledge proof used for ML-DSA is only able to prove something about a specific LWE problem as used in ML-DSA: the proof uses mathematical structure in the key. There are ways to create zero-knowledge proofs using lattices for any general statement, but those proof systems are very different from ML-DSA, and would create rather larger signatures on the order of 50kB.
In contrast, the proof system used in FAEST, MQOM, and SDitH can be used to prove arbitrary statements. For instance, FAEST can be modified to use the hard problem of MQOM instead. This leads to a more efficient scheme called KuMQuat. (We’ll get to some performance numbers later on.) Conversely, MQOM can be adjusted to use AES as the hard problem.
This flexibility is great for two reasons. First, it doesn’t require any specific mathematical structure in the hard problem used, and thus we can pick a very conservative problem such as breaking AES. Some problems lead to a more efficient signature than others, as we see with MQ as used in MQOM. MQ is still quite a conservative assumption: it does not contain the hidden subspace used in UOV and thus the other multivariate signatures. Neither the intersection nor wedges attacks apply to it. In fact, the MQ-problem is NP-hard. To be secure, one still needs to pick the correct size of the problem, and although MQ has been studied for quite a while, it certainly has not seen the same scrutiny as deployed algorithms like AES.
The second and greater benefit is that we’re able to create much more than just a plain signature scheme from a general zero-knowledge proof system: we can create blind signatures and even full-fledged anonymous credentials.
Here it’s good to note a limitation: the size of the proofs for all three grows linearly with the statement proven. In technical terms: they’re not succinct like STARKs and LaBRADOR, which outperform them handily for large statements. It’s another example where sometimes it’s better to pick the approach that’s not optimal asymptotically.
Back to advantages: apart from the hard problem chosen, and the security of hash functions, these three schemes don’t require any further security assumption. This makes FAEST as conservative as SLH-DSA.
So what’s the difference except for the chosen hard problem? These schemes started off quite differently, but have been improving and converging since the first round. The proof system in MQOM is a bit simpler than FAEST, but it also does not perform as well: KuMQuat (FAEST+MQ) outperforms MQOM.
Talking about performance, let’s start with a comparison to SLH-DSA. All three schemes have variants that outperform any standardised SLH-DSA parameter set and often by a good margin. SLH-DSA does have one distinct advantage: the verification routine is simpler to implement.
Against ML-DSA-44 the comparison is more interesting. All schemes have a smooth trade-off between runtime and signature size. To illustrate, here are trade-offs reported for KuMQuat (FAEST+MQ.) Verification times are close to signing times.
KuMQuat can be parametrized to have somewhat smaller signatures than ML-DSA-44 at the cost of long signing (and verification) runtime. At the other end, it can have similar signing time as ML-DSA-44, at the cost of larger signatures, although the public key+signature size is still similar.
These schemes have improved quite a bit over the years, and we expect some improvements still. Although they won’t improve upon ML-DSA as dramatically as some of the other schemes considered, their conservative security and especially their potential for broader applications like anonymous credentials make them very appealing. To showcase the flexibility of the underlying zero-knowledge proof system, we’d like each scheme in this category to present numbers on how well they’d perform with a different underlying hard problem.
Structured multivariate: MAYO versus SNOVA
Like QR-UOV discussed earlier, MAYO and SNOVA are variants of UOV that add extra structure to the public key to reduce its size. MAYO and SNOVA take two different approaches: SNOVA makes aggressive bets to get the best performance, whereas MAYO treads carefully with a conservative design.
SNOVA does have impressive performance. Its main parameter set has 248 byte signatures (smaller than RSA-2048!) with only a 1kB public key. It beats every other post-quantum scheme on public key+signature size and has great runtime.
MAYO’s performance is nothing to scoff at either. MAYOone has the best verification time and its 454 byte signatures are still smaller than those of FN-DSA-512, HAWK-512, and RSA-4096. Combined with its 1,420 byte public key, MAYOone does slightly fall behind FN-DSA-512 and HAWK-512. However, MAYO takes the lead again if we ask for some security margin. FN-DSA and HAWK have a missing middle security level and thus need to bump all the way to the 256-bit security, whereas MAYO’s granularity can add extra security at the cost of slightly increasing public key and signature sizes.
Security
Public key
Signature
PK + Sig
HAWK-1024
256
2,440
1,221
3,661
FN-DSA-1024
256
1,793
1,280
3,079
MAYO at 174 bit security
174
1,600
550
2,150
If that wasn’t good enough, both MAYO and SNOVA allow for a trade-off between signature and public key size. Thus, we can get even smaller signatures for public keys that are transmitted ahead of time. Pushed to the extreme, MAYO becomes UOV.
So far we have discussed performance. What about the security? MAYO adds a “whipping” structure on top of UOV: any attack on UOV will also work for MAYO, but there might be attacks specific to the whipping structure of MAYO. So far no attacks on the whipping structure, and thus on MAYO specifically, have been found. The worst that has happened is that some UOV attacks have affected some MAYO variants more than typical UOV parameter sets, due to the UOV parameter choices that are natural for MAYO.
This is in stark contrast to SNOVA. SNOVA has been hit quite hard on its specific structure several times. In response, the SNOVA team has not just tweaked parameters, but continuously changed the actual structure. Every time, they take the leap forward and propose a new SNOVA with even better performance. We noted this last year and the pattern has continued, whereas MAYO’s basic design is stable.
Furthermore, the structure SNOVA uses can beseen as a special form of the whipping map that MAYO uses. That means that any MAYO-specific attack would apply to SNOVA, but not the other way around.
All in all, we’ve seen a lot of progress on the understanding of multivariate security. NIST wrote that they expect an extra round before standardizing a multivariate scheme. That seems prudent. To us, it’s unclear whether SNOVA would be ready by then, but MAYO so far seems to have matured well.
Timelines
Now, let’s have a look ahead and sketch when these new signature algorithms might become usable.
Progress for ML-DSA so far
It’s illustrative to look at ML-DSA.
November 2017
Submitted to the competition
January 2019
Progressed to the second round
July 2020
Progressed to third round
July 2022
Selected for standardization
August 2023
Initial public draft
August 2024
Final NIST standard
October 2025
ML-DSA certificate standard (RFC 9881)
April 2025
OpenSSL 3.5.0 adds support for ML-DSA
August 2025
Debian Trixie released with OpenSSL 3.5.0
December 2025
TLS IANA codepoint for ML-DSA registered
March 2026
First CMVP certificates for ML-DSA module
July 2026 (expected)
Hybrid ML-DSA certificate standard
August 2026 (expected)
RFC for use of ML-DSA in TLS
Early 2027 (expected)
Availability first ML-DSA certificates in WebPKI
After NIST selected Dilithium to become ML-DSA, it took a year to draft a proposal for the standard, and another year for the algorithm standard to be published. The algorithm standard is not enough: protocols need to agree on how to integrate ML-DSA. For certificates that took another year. That’s not the end of it: software needs to add support for ML-DSA and its integration into protocols.
These steps are not purely sequential: work on software implementation of ML-DSA started before the final standard. Also, protocol integration standards are often “done” before they’re a final standard. For instance, the use of ML-DSA in TLS is done, but at the time of writing it’ll take a couple of months before the RFC for that is out. Notably OpenSSL jumped the gun and added support for ML-DSA before the IANA codepoints were assigned. Notably missing still is agreement on which hybrid signatures should be used in TLS (or at all), for which (at the time of writing) no IANA code points have been assigned.
When will these new signature algorithms be ready for use?
So where does that leave us for new signature algorithms? If the FN-DSA draft is released today, and it progresses at the same rate as ML-DSA, then we’d perhaps have some early software support in early 2029, but no significant deployment. Looking at the time it took to write the FN-DSA draft standard, it is likely that the final standard, protocol integrations, and software support will progress slowly as well. We would not expect FN-DSA to be widely available before 2033.
The progress in cryptanalysis of multivariate schemes gave NIST pause: they wrote that they expect multivariate to at least take another round of about two years. On the other hand, multivariate schemes are reasonably easy to implement. That means we might see a multivariate NIST standard in 2031, and wider product availability not earlier than 2034.
NIST is more confident in the security of SQIsign than that of multivariate. Not unlike FN-DSA, SQIsign is a difficult scheme to standardise and implement. At the same time, a lot of progress is made in simplifying SQIsign. It seems likely that SQIsign will make large changes for the third round, and will thus require a fourth round of evaluation. In either case, wide availability before 2035 seems unlikely.
As discussed above, HAWK occupies an awkward middle ground between FN-DSA and structured multivariate candidates. If it were standardized, which seems unlikely even before the recent progress in cryptanalysis, we wouldn’t expect product availability before 2034.
That leaves the proof of knowledge algorithms MQOM, SDitH, and FAEST. We’ve seen dramatic improvements to these schemes over the rounds. If that rate of change holds, it’ll require another round, but if it’s stable now, a proof of knowledge algorithm will be the first new NIST standard to see the light in 2030. If it’s out this early, it’ll likely not outperform ML-DSA dramatically. Nonetheless, it’ll still be very welcome to build anonymous credentials and other primitives beyond signatures.
So, should you wait on one of these signatures for your post-quantum migration? Given recent advances in quantum hardware and software, we don’t believe we can afford to wait. At Cloudflare, we’re aiming to be fully migrated by 2029. None of these signatures will be out in time. Deadlines of most regulators vary between 2030 and 2035. These did not account for recent progress, and we expect them to be adjusted. We saw just this with the June 2026 US executive order setting a 2031 deadline. Even if deadlines weren’t changed, we wouldn’t advise waiting.
Why? Deploying post-quantum signatures in 2034 to beat a 2035 deadline is not enough. In a system of any reasonable size, you can’t upgrade everything all at once. You’ll need a transition period where both post-quantum and traditional signatures are supported. And supporting both allows for a downgrade attack. The most straightforward way to prevent such downgrades is to disable classical cryptography. That will take time, and is frankly not even an option in many sufficiently distributed systems like the WebPKI. We will cover how to deal with downgrades in a future blog post. In the meantime here is some reading if you’re curious. In any case, dealing with downgrades will take time.
It seems clear these new post-quantum signature algorithms will not be ready to use in time for the first migration. So why bother?
Why we still need them
We’ve had 50 years to weave public key cryptography all through our digital society. We have a few short years left to make it all quantum secure. For most of these upgrades the procedure is clear: drop in post-quantum cryptography. Easier said than done: it’s a monumental task. But then there are cases that are fundamentally harder. There’s no all-star signature in a post-quantum world, and there are cases where the size of ML-DSA is a problem. With enough resources and stakeholder agreement, systems can be re-engineered to work well with these larger signatures. Indeed, thanks to ongoing re-engineering, the post-quantum WebPKI is shaping up to perform better than the quantum-vulnerable one of today. It is unrealistic to expect that this will happen for every system before it’s too late. Some will have to accept a performance cost. Others will need to deal with the security gap in other ways, such as restricting access, tunneling, more monitoring, or a myriad of other measures that are costly on their own. Once smaller post-quantum signatures arrive, these compensating controls can be removed, and full efficiency and security restored.
An indirect, but no less important benefit of the ongoing NIST competition is its help in furthering post-quantum cryptography beyond basic primitives: it isn’t just key agreement and signatures that are quantum vulnerable. There is a long tail of fancy cryptographic primitives out there used in production, such as anonymous credentials, PAKEs, and threshold signatures to name a few. For most, post-quantum variants are not readily available or are understudied. For some, the same goal can be achieved without fancy cryptography, but with a regrettable regression in subtle privacy goals. NIST cannot run a competition to define a post-quantum standard for each of these specific primitives, but luckily the signatures competition has been a huge help here.
The most clear example is FAEST. Although designed as a signature scheme, its underlying machinery (VOLEitH) can be repurposed in combination with a multivariate scheme like MAYO, to create an efficient post-quantum anonymous credential. Without the signatures competition, VOLEitH wouldn’t be as developed and vetted as it is today.
Many of the candidate schemes briefly point out their usefulness apart from signatures. We hope to see more of the indirect applications of these schemes highlighted.
Despite great signatures and more advanced cryptography on the horizon, we should not forget the task at hand: staying secure in the immediate future.
Interesting research on a new class of weak RSA keys: keys with lots of zeros. It turns out that these keys are out in the wild.
The badkeys project is an open-source service that checks public keys for known vulnerabilities. While developing this tool, Hanno collected a massive number of real-world keys from public sources, including Certificate Transparency logs, internet-wide TLS and SSH scans, PGP keys, and many others. By searching this dataset for unexpectedly sparse RSA moduli, we uncovered a large number of keys in the wild with the patterns in Figure 1.
Both patterns include several regularly spaced blocks of all zeros interleaved with seemingly random data. Pattern 1 appears in CT logs for certificates issued to several large organizations, including Yahoo and Verizon, and on some devices running NetApp software. Fortunately, these certificates have already expired, but we still shared our findings with these companies. We wanted to learn more about which product could be responsible for generating these keys, but we did not hear back. Pattern 2 appears on SSH hosts running the CompleteFTP software from EnterpriseDT. The underlying vulnerability affects RSA keys generated using versions 10.0.012.0.0 (Dec 2016Mar 2019) and DSA keys generated with v10.0.023.0.4 (Dec 2016Dec 2023).
These vulnerabilities affect a small minority of hosts on the internet, but the more interesting takeaway is that independent cryptographic implementations failed in similar ways. More implementations may include the same bugs, and so it’s worth tailoring cryptanalytic algorithms for this particular type of failure.
The article doesn’t speculate, but I will. This could be a deliberately designed backdoor, of the sort I wrote about back in 2013. I could imagine some government agency figuring out how to break this class of RSA keys, and then convincing different providers to hand them out to users.
On June 22, 2026, President Trump signed Executive Order 14409, “Securing the Nation Against Advanced Cryptographic Attacks.” The order sets a December 31, 2030, deadline for federal agencies to transition their most sensitive systems to post-quantum encryption, and a December 31, 2031, deadline for post-quantum authentication. The EO also directs federal contractors to comply with post-quantum Federal Information Processing Standards (FIPS) by the end of 2030.
We welcome this executive order. The U.S. government has a long track record of using federal leadership and procurement to drive adoption of new technologies across the broader industry. We’ve seen this work with IPv6, with routing security and the Resource Public Key Infrastructure (RPKI), and with DNSSEC, and we’re glad to see this tradition continue with post-quantum cryptography.
The EO is especially important at this moment because the timeline for Q-Day, the day that quantum computers can break the public-key cryptography used across the Internet, has been accelerated. In April 2026, Cloudflare moved our own target for full post-quantum security to 2029, following research breakthroughs from Google and Oratomic. This EO updates guidance from 2024, when the National Institute of Standards and Technology (NIST) stated that the classical public key cryptography used across the Internet (namely RSA and Elliptic Curve Cryptography, which can be broken once powerful quantum computers become available) should be deprecated by 2030 and disallowed by 2035.
The Internet’s transition to post-quantum encryption is well underway, while the transition to post-quantum authentication has only just begun. Today, over two-thirds of browser traffic to Cloudflare’s network is protected with post-quantum encryption, and most of our products support post-quantum key agreement. Our SASE platform, Cloudflare One, provides post-quantum encryption across all major on-ramps and off-ramps, including TLS, MASQUE, and IPsec. We’ve recently started deploying post-quantum authentication and aim to be fully post-quantum secure by 2029. The EO is an excellent foundation and builds on work from the previous two Administrations. We’ve been doing the work the EO is asking federal agencies to do since 2019, we have some thoughts on what the order gets right, we see opportunities for the Office of Management and Budget (OMB) to strengthen and facilitate cost-effective agency migration, and we provide a roadmap for how organizations and agencies can advance their transition most effectively.
The EO’s requirements for federal systems
The bulk of the EO’s binding requirements are aimed at two categories of federal systems: High Value Assets (HVAs) and high impact systems. HVAs are federal information or systems designated by OMB as the government’s crown jewels: systems whose compromise would significantly affect national security, foreign relations, or public confidence. These include databases that hold millions of federal employee records, systems that process classified intelligence, or platforms that manage federal financial transactions. Meanwhile, high impact systems are those where confidentiality, integrity, or availability is rated “high” under FIPS 199, meaning a breach could cause severe harm including loss of life, major financial damage, or significant degradation of an agency’s ability to carry out its mission.
The EO has the power to bind federal agencies, but not other organizations (i.e., critical infrastructure, state, local, tribal and territorial governments, academia, civil society). That’s why the EO only gives these deadlines to federal agencies:
Date
Requirement
July 2026
Each federal agency head identifies a PQC migration lead and provides their name and contact details to OMB and the National Cyber Director.
September 2026
OMB issues guidance requiring each agency to: (1) review their inventory of HVAs and high impact systems; (2) plan for PQC migration; and (3) submit that plan to OMB and the National Cyber Director.
December 2030
All HVAs and high impact systems must be transitioned to PQC for key establishment.
December 2031
All HVAs and high impact systems must be transitioned to PQC for digital signatures.
National Security Systems are explicitly excluded from these deadlines. They are on a separate, classified track managed by the NSA with deadlines between 2030 and 2033 already set in 2022.
Two migrations: encryption and authentication. Both should begin now.
The EO splits the PQC migration into two phases: post-quantum key establishment (encryption) by 2030, and post-quantum digital signatures and certificates (authentication) by 2031. This accurately reflects the availability of post-quantum encryption across the Internet today. Our own deadline for full post-quantum readiness (including authentication) is 2029, but we are amongst the earliest adopters in the industry.
Now let’s have a deeper look at the two migrations called for and required in the EO: post-quantum encryption and post-quantum authentication.
Post-quantum encryption is needed today to stop harvest-now-decrypt-later attacks, where an adversary collects encrypted traffic today and decrypts it later once quantum computers are powerful enough. Post-quantum encryption is especially valuable for organizations handling data that will still have value to adversaries 3-10 years from now, like government agencies, banks, healthcare organizations, defense contractors, and telecom providers.
Post-quantum authentication stops an adversary that has a quantum computer from forging certificates to impersonate servers, generating malicious code signatures, or gaining unauthorized access to systems. Post-quantum authentication is needed only after Q-Day risk materializes, because it stops attacks that are possible only once a cryptographically-relevant quantum computer (CRQC) exists.
It’s important to put the migration timelines in context with advancements in quantum computing. In addition to yesterday’s EO on post-quantum security, President Trump also signed an EO to accelerate deployment and commercialization of quantum computing, sensing, and networking. The fact that the EO sets a 2031 deadline for post-quantum authentication tells us something important: the U.S. government believes there is a non-negligible chance that a CRQC could be operational around that time.
What about the state of these two technologies? The migration to post-quantum authentication is a bigger challenge than post-quantum encryption for a few reasons, including:
Post-quantum ML-DSA digital signatures are larger than classic digital signatures, which could have an impact on performance of some systems, for instance in short-lived TLS connections. That’s why we are working with Google Chrome on Merkle Tree Certificates to solve the performance problem for TLS.
There is only limited ecosystem deployment of post-quantum authentication so far, as compared to the much broader deployment of post-quantum encryption.
It is interesting that the EO sets a one-year gap between the encryption and authentication deadlines. One extra year of calendar time is tight, so this work cannot proceed sequentially. The ecosystem needs to start working on both of these targets concurrently, or we will miss this 2031 deadline.
Cryptographic deployment across the Internet cannot happen without standards developed by the Internet Engineering Task Force (IETF). They are working to transition their protocols to post-quantum cryptography. The TLS community is ahead, with the IETF PLANTS working group making good progress on post-quantum certificates for TLS. There is much work to do here and we look forward to supporting the IETF in its efforts.
Supply chain pressure that helps everyone
The EO includes requirements for federal contractors, which may turn out to be the most impactful part of the EO.
Namely, the FAR Council must publish proposed rules requiring “covered contractors” to comply with NIST FIPS incorporating PQC algorithms by December 31, 2030 (Sec. 6(c)). The FAR Council must also publish proposed rules requiring contractors to implement vulnerability disclosure programs that cover cryptographic vulnerabilities (Sec. 6(d)). These proposed rules need to go through notice-and-comment rulemaking, but the EO has a December 31, 2030 target which is still important. This deadline is one year earlier than federal agencies are required to complete their post-quantum authentication migration, so that federal contractors will be ready before agencies hit their own deadlines.
Federal agencies can only migrate to PQC if the products they buy support PQC. To put this into practice, CISA released its Product Categories for Technologies That Use Post-Quantum Cryptography Standards, drawing a clear line between technologies where PQC is already “widely available” versus those still “transitioning.” The “widely available” list includes cloud platforms (IaaS, PaaS), web browsers and servers, chat and messaging software, and endpoint security products like full disk encryption. For these categories, CISA’s guidance is clear: organizations should procure only PQC-capable products. The “transitioning” list, where PQC is not yet widely available, includes networking hardware (routers, firewalls, switches), identity and access management systems (HSMs, certificate authorities, identity providers), email servers and clients, and database systems.
By telling contractors their products must be PQC-compliant by 2030, and directing agencies to immediately favor PQC-capable vendors in mature markets, the federal framework forces the vendor ecosystem to ship PQC-capable products on a fixed timeline. Products that vendors build to federal requirements will end up used by hospitals, banks, universities, and small businesses, which makes PQC support more broadly available. Cloudflare is among the many vendors subject to these requirements, and because networking software and cloud services are already designated by CISA as widely available PQC categories, we’ve already shipped post-quantum encryption across most of our products at no extra cost.
Critical infrastructure and PQ for everyone
The EO also speaks to critical infrastructure: energy, financial services, water, transportation, telecommunications, healthcare, and other systems whose failure would have a serious or significant impact on the country. While the EO has no hard migration deadline for critical infrastructure owners and operators, the EO directs certain federal agencies to “assist” critical infrastructure owners and operators with their PQC migration plans (Sec. 5(a)).
While the EO focuses mostly on federal agencies and critical infrastructure in the U.S., post-quantum cryptography is important to every Internet-connected individual and organization. Harvest-now-decrypt-later attacks are a risk today. And after Q-Day, the risk of unauthorized access by an adversary armed with a quantum computer will impact any organization, big or small. When we launched free universal SSL in 2014, our CEO Matthew Prince wrote:
Having cutting-edge encryption may not seem important to a small blog, but it is critical to advancing the encrypted-by-default future of the Internet. Every byte, however seemingly mundane, that flows encrypted across the Internet makes it more difficult for those who wish to intercept, throttle, or censor the web.
We feel the same way about post-quantum cryptography. That’s why every post-quantum upgrade we build is available to all customers, on every plan, at no additional cost.
Opportunities for OMB’s implementation guidance
The EO sets the direction, and now OMB has 90 days to provide important clarifications and operational guidance to achieve the most effective PQC migration across federal agencies (Sec. 4(b)). Based on what we’ve learned from our own PQC migration, here are a few elements that we suggest that guidance should include:
Define what it means to “transition.” The EO requires agencies to “transition” their systems to PQC, but it never defines what “transition” means. Does it mean the system supports PQC algorithms? That it prefers them? Or that classical cryptography has been disabled entirely?
These are very different security postures. A system that supports ML-KEM but still allows a classical-only TLS handshake is vulnerable to downgrade attacks. An adversary capable of intercepting traffic could force the connection back to classical key exchange. The system would have “transitioned” to PQC in name, but still be vulnerable to the same quantum attacks the order is trying to prevent.
History is instructive. When SSLv3 was deprecated after the POODLE attack in 2014, servers kept SSLv3 enabled for backwards compatibility, allowing attackers to force connections to downgrade and then exploit SSLv3’s weaknesses. It took years for the ecosystem to actually turn SSLv3 off. To avoid repeating this pattern, we need a clear definition of “done” that includes disabling quantum-vulnerable cryptography to prevent downgrades.
Crypto agility: Crypto agility is the ability to swap cryptographic algorithms without re-architecting your systems. The EO mandates migrating to specific NIST crypto standards, but says nothing about building systems that can swap cryptographic algorithms if these algorithms need to change in the future. Crypto agility doesn’t mean supporting every algorithm at once. It means building systems so that when the community converges on a better algorithm in the future, the upgrade is a configuration change, not a re-architecture. The OMB should include this in its guidance.
CBOM or quantum impact inventory? The EO directs CISA and NIST to publish guidance on the minimum elements for a cryptographic bill of materials (CBOM) within 270 days (Sec. 5(d)). A CBOM is an inventory of the cryptographic algorithms, protocols, and implementations used in a given hardware or software product, similar to a software bill of materials (SBOM).
In theory, CBOMs are a good idea. In practice, we’d caution against treating exhaustive cryptographic inventories as a prerequisite for action. A detailed CBOM of every algorithm in every library in every product takes a long time to produce, it can take federal agencies an entire procurement cycle of discovery tooling and consulting, and it potentially becomes stale by the time the inventory is complete. Also, a CBOM doesn’t list systems that should be using cryptography but are not. And a CBOM lists keys without an understanding of their purpose, making them less useful for organizations trying to understand the risk associated with a quantum-vulnerable key.
We think that a quantum impact inventory is a more productive framing. What would be the impact if the system or its data is compromised? How likely is that to happen? What measures can be taken to mitigate the risk, whether a drop-in replacement, a software update, or a compensating control like tunneling traffic over bulk post-quantum connection or isolating it from the Internet? How feasible is each option and what dependency chain does it create? Identifying these informs where to take action first. You can fill in the details of a full CBOM over time if that makes sense for your organization, but you should start by discovering your most exposed and impactful systems.
Making post-quantum cryptography affordable to all. True national resilience fails if post-quantum cryptography is treated as a gated luxury rather than a universal baseline. OMB policy must resist vendor lock-in or toll booths that leave underfunded critical infrastructure behind or increase technical debt at federal agencies.
What to do now: don’t wait for 2030
You do not have to wait for 2030 or an exhaustive cryptographic inventory to start your migration. History has shown that updating cryptography is hard and can take a longtime; other organizations should start sorting out their migrations as well. So as we wait for OMB guidance for federal agencies, here’s what we recommend for all organizations:
Protect your Internet traffic now. Start with traffic that crosses the public Internet, because that is the easiest for adversaries to harvest now and the most immediately at risk. If your web traffic flows through Cloudflare, your connections are largely protected with post-quantum encryption. If your enterprise network uses Cloudflare One, your private network traffic is also protected. If your provider doesn’t support post-quantum encryption, switch to one that does. Even if the individual applications running inside your network haven’t been upgraded yet, start tunneling your traffic through post-quantum encrypted infrastructure to protect it in bulk, even if individual systems are not yet inventoried and upgraded.
Update procurement. Make “post-quantum encryption by default, at no additional cost, with a clear roadmap for post-quantum authentication and crypto agility” a requirement in every technology procurement. If your vendor charges extra for post-quantum security or doesn’t have a roadmap or plan, ask why or find another vendor.
Quantum impact inventory. For traffic that stays inside your private network perimeter and is not exposed to the public Internet, the harvest-now-decrypt-later risk is lower because an adversary would need to be on your network to capture it. But you still need to know what cryptography your internal systems use, so you can plan your migration. Use a quantum impact inventory as a tool to prioritize your efforts, for example focusing on systems or connections that handle sensitive data or are exposed on the public Internet.
Plan for authentication now. The 2031 deadline for post-quantum authentication will come faster than you think. Start identifying your long-lived keys, root certificates, and code-signing infrastructure. These are the highest-priority targets for a quantum attacker, and they have the longest dependency chains to upgrade. Now is a great time to update your software libraries and automate certificate provisioning even if post-quantum certificates are not yet available in your ecosystem. And make sure your vendors are planning to be ready for the looming post-quantum authentication deadline.
Aligning policy and international standards
At the same time, work should also start now on aligning global government policy with international standards. We were glad to see that Section 5(b) directs the State Department to engage foreign governments and industry groups to encourage adoption of NIST-standardized PQC algorithms.
Here’s why this matters. Cryptography migrations cannot be run in a vacuum, with each country operating within its own borders. A TLS connection between a U.S. person and a server abroad only works if both ends negotiate the same cryptography. NIST has been running open international cryptographic competitions for decades. The AES competition (1997-2001) produced the encryption standard used across the Internet today, selecting a cipher designed by Belgian cryptographers. The SHA-3 competition (2007-2012) produced the latest hash standard, selecting an algorithm designed by a Belgian-Italian team. The PQC competition (2016-2024) followed the same open model: anyone could submit, anyone could analyze, and the winning algorithms were designed by international teams. ML-KEM, the key agreement standard now being deployed across the Internet, was created largely by European cryptographers. These are open, internationally vetted algorithms. NIST organized the competitions, but the results belong to the global cryptographic community.
The risk ahead is fragmentation. If different jurisdictions mandate different algorithms, the result is cipher bloat and increased attack surface: more code to write, test, and audit, more surface for downgrade attacks, and slower deployment for everyone. We’ve seen this happen firsthand in IPsec, where the lack of an interoperable standard led vendors to ship proprietary PQ key agreement algorithms that couldn’t interoperate, delaying the migration by years. The TLS community went the opposite way, converging on a single hybrid key agreement (X25519MLKEM768), and deployment followed quickly.
We are big fans of NIST, and especially its leadership in vetting standards globally and standardizing cryptography worldwide. We encourage the Trump Administration to work with Congress to ensure that NIST has appropriate resources, staffing, and tooling to meet current and emerging deliverables in this EO and others, like America’s AI Action Plan.
We’d like to see State Department-led engagement drive real alignment: adoption of the same NIST algorithms across allied nations, alignment on timelines, and mutual recognition of cryptographic algorithms and modules. The Internet is one network, and its cryptography should be one standard.
Speeding up CMVP
As a final note, the EO directs NIST to revise the processes used by the Cryptographic Module Validation Program (CMVP) to accelerate validations of cryptographic modules (Sec. 6(b)). Having bumped up against the CMVP program for years, we are extremely happy to see this in the order.
CMVP exists for a good reason. Federal agencies and their contractors need a way to verify that the cryptography inside a product actually does what it claims: that AES is implemented correctly or that random number generators have enough entropy. CMVP has been tuned for a steady state where cryptography doesn’t change much.
Going forward, CMVP needs to be adjusted to accept the realities of the impending migration. We welcome the FedRAMP update stream that allows updated modules to be used immediately before final validation. This allows faster adoption of post-quantum cryptography, and correction of implementation errors that were missed in validation. Similar allowances for CMVP are essential.
Go forth and PQ all the things
This post-quantum EO is a meaningful step. It sets real deadlines and creates supply chain pressure that will accelerate adoption across the industry.
For organizations starting their own migration, we suggest you start by protecting your public Internet traffic along with updates to your procurement requirements, followed by a quantum impact inventory to figure out where to focus next. Do not let cryptography inventory slow you down from deploying post-quantum encryption across your most sensitive systems immediately.
Cryptographic deployment across the Internet depends on standards developed by the IETF. The TLS community isfurther along, but there is lots more work to do across other protocol communities, and we look forward to supporting those efforts.
Let us go forth and PQ all the things, quickly and together. Free TLS helped encrypt the web. Free post-quantum cryptography will help secure it for what comes next.
You can get started now on Cloudflare by visiting our PQC page.
As part of their 20th Anniversary celebration, Dark Reading asked five cybersecurity industry leaders who wrote blogs or columns for them over the years to select their favorite piece and share their reflections on the topic today. This is my section.
Renowned technologist and author Bruce Schneier contributed a column on June 20, 2010, warning about cryptography’s inability to secure modern networks, a point he says he has been trying to argue since 2000.
“For a while now, I’ve pointed out that cryptography is singularly ill-suited to solve the major network security problems of today: denial-of-service attacks, website defacement, theft of credit card numbers, identity theft, viruses and worms, DNS attacks, network penetration, and so on.
“Recently, I talked to a former NSA employee at a conference. He told me that back in the 1990s, he had a copy of my book Applied Cryptography by his desk, as did many other cryptographers working at Ft. Meade. People were allowed to refer to it, but they were not allowed to cite it.
“The 1990s were an important decade for cryptography. This was before the internet went mass market, when cryptography was just emerging from a niche academic discipline to a mainstream engineering one. There wasn’t much that programmers could read. The NSA used my book for the same reason it became a bestseller: because it collected all the academic cryptography of the time in one place and made it understandable to people who weren’t mathematicians. They feared it for exactly the same reason.
“I’ve been thinking about that conversation as I revisit a 2010 essay I wrote for Dark Reading, ‘The Failure of Cryptography to Secure Modern Networks.’ Cryptography has inherent mathematical properties that greatly favor the defender. Adding a single bit to the length of a key adds only a slight amount of work for the defender but doubles the amount of work the attacker has to do. Doubling the key length doubles the amount of work the defender has to do (if that—I’m being approximate here) but increases the attacker’s workload exponentially. For many years, we have exploited that mathematical imbalance.
“Computer security is much more balanced. There’ll be a new attack, and a new defense, and a new attack, and a new defense. It’s an arms race between attacker and defender. And it’s a very fast arms race. New vulnerabilities are discovered all the time. The balance can tip from defender to attacker overnight, and back again the night after. Computer security defenses are inherently very fragile.
“That isn’t a new idea. I said much the same thing in the preface to my 2000 book, Secrets and Lies:
“‘Cryptography is a branch of mathematics. And like all mathematics, it involves numbers, equations, and logic. Security, real security that you or I might find useful in our lives, involves people: things people know, relationships between people, people and how they relate to machines. Digital security involves computers: complex, unstable, buggy computers.’
“I especially like how I phrased it in 2016: ‘Cryptography is harder than it looks, primarily because it looks like math. Both algorithms and protocols can be precisely defined and analyzed. This isn’t easy, and there’s a lot of insecure crypto out there, but we cryptographers have gotten pretty good at getting this part right. However, math has no agency; it can’t actually secure anything. For cryptography to work, it needs to be written in software, embedded in a larger software system, managed by an operating system, run on hardware, connected to a network, and configured and operated by users. Each of these steps brings with it difficulties and vulnerabilities.’
“It’s a lesson we have all learned over the decades. Cryptography is still necessary for cybersecurity—although I wouldn’t have used that word back then—but is not sufficient. There are particular attack and forms of mass surveillance that cryptography prevents. But as computers have infused throughout our lives, and networks have connected all those computers, those aspects of cybersecurity have become increasingly important, and vulnerable.
“Today, the cybersecurity world is changing yet again, this time due to the capabilities of artificial intelligence. AI isn’t advancing cryptography, but it’s changing cybersecurity. AI has demonstrated a superhuman ability to find vulnerabilities in software and to write exploits. A similar ability to write patches is probably coming. This has profound implications for both attackers and defenders, and it is unclear who will win the particular arms race in a world of what I call instant software.”
While more than two-thirds of human-generated TLS traffic to Cloudflare is already protected by post-quantum cryptography, the world of site-to-site networking has been a different story. For years, the IPsec community remained caught between the high bar of Internet-scale interoperability and the niche requirements of specialized hardware. That gap is now closing.
Earlier this month, we announced that Cloudflare has moved its target for full post-quantum security forward to 2029, spurred by several recent advances in quantum computing. To advance that goal, we’ve made post-quantum encryption in Cloudflare IPsec generally available.
Using the new IETF draft for hybrid ML-KEM (FIPS 203), we’ve successfully tested interoperability with branch connectors from Fortinet and Cisco — meaning you can start protecting your wide-area network (WAN) against harvest-now-decrypt-later attacks today using hardware you already have.
This post explains how we implemented the new hybrid IPsec handshake, why it took four years longer to land than its TLS counterpart, and how the industry is finally consolidating around a standard that works at Internet scale.
Cloudflare IPsec
Cloudflare IPsec is a WAN Network-as-a-Service that replaces legacy network architectures by connecting data centers, branch offices, and cloud VPCs to Cloudflare’s global IP Anycast network. Customers get simplified configuration, high availability (if a data center becomes unavailable, traffic is automatically rerouted to the nearest healthy one), and the scale of Cloudflare’s global network. This is done through encrypted IPsec tunnels that support both site-to-site WAN, outbound Internet connections, and connectivity to the Cloudflare One SASE platform.
Post-quantum encryption in IPsec
Cloudflare IPsec now uses post-quantum encryption with hybrid ML-KEM (FIPS 203) to stop harvest-now-decrypt-later attacks. These are attacks where an adversary harvests data today and then decrypts later, after Q-Day, when there are powerful quantum computers that can break the classical public key cryptography used across the Internet. Harvest-now-decrypt-later attacks are becoming a concern for more organizations as Q-Day approaches faster than expected.
ML-KEM (Module-Lattice-Based Key-Encapsulation Mechanism) is a post-quantum cryptography algorithm that is based on mathematical assumptions that are not known to be vulnerable to attacks by quantum computers. It does not require special hardware or a dedicated physical link between sender and receiver. ML-KEM is intentionally designed to be implemented in software across standard processors to provide post-quantum encryption of network traffic.
Draft-ietf-ipsecme-ikev2-mlkem specifies post-quantum encryption for IPsec using hybrid ML-KEM, which combines the well-understood security of classical Diffie-Hellman and the post-quantum security of ML-KEM in a single, standards-compliant handshake. Specifically, a classical Diffie-Hellman exchange runs first, its derived key encrypts a second exchange that runs ML-KEM, and the outputs of both are mixed into the session keys that secure IPsec data plane traffic sent using the Encapsulating Security Payload (ESP) protocol.
Our interoperable implementation
Earlier we announced the closed beta of our implementation of draft-ietf-ipsecme-ikev2-mlkem in production in our Cloudflare IPsec product and tested it against a reference implementation (strongswan). Now that we have made this implementation generally available, we have also confirmed interoperability with several other vendors, including Cisco and Fortinet, which is a big win for this new standard.
Fortinet: Customers using Fortinet FortiOS 7.6.6 and later as their branch connector can now establish post-quantum Cloudflare IPsec tunnels to Cloudflare’s global network per draft-ietf-ipsecme-ikev2-mlkem.
The importance of being interoperable
Given that upgrading cryptography is hard and can take years, our 2029 target date for a full update to post-quantum cryptography is going to require concentrated effort. That’s why we hope the IPsec community continues to focus on the development of interoperable standards like draft-ietf-ipsecme-ikev2-mlkem.
Let us explain why these standards are vitally important. A full specification for hybrid ML-KEM in IPsec, draft-ietf-ipsecme-ikev2-mlkem, became available only in late 2025. That’s roughly four years after support for hybrid ML-KEM landed in TLS. (In fact, Cloudflare turned on hybrid post-quantum key agreement with TLS in 2022, even before NIST finalized the standardization of ML-KEM, because the TLS community quickly converged on a single, interoperable approach and pushed it into production. Today more than two-thirds of the human-generated TLS traffic to Cloudflare’s network is protected with hybrid ML-KEM.)
The four-year delay is likely due in part to the IPsec community’s continued interest in Quantum Key Distribution (QKD), as codified in RFC 8784, published in 2020. We’ve written before about why QKD is not part of our post-quantum strategy: QKD requires specialized hardware and a dedicated physical link between the two parties, which fundamentally means it will not operate at Internet scale. Also, QKD does not provide authentication, so you still need post-quantum cryptography anyway to stop active attackers. It’s difficult to find implementations of QKD that interoperate across vendors.
The U.S. NSA, Germany’s BSI, and the UK’s NCSC have all warned against solely relying on QKD. Post-quantum cryptography, by contrast, runs on the hardware you already have, authenticates the parties at both ends, and works end-to-end across the Internet.
RFC 9370, published in 2023, opened the door to post-quantum cryptography in IPsec, allowing up to seven key exchanges to be run in parallel with classical Diffie-Hellman. However, RFC 9370 did not specify which ciphersuites should be used in these parallel key exchanges. In the absence of that specification, some vendors shipped early implementations under RFC 9370 before the hybrid ML-KEM draft was available, defining their own ciphersuites including some which are not NIST-standardized. This is exactly the kind of “ciphersuite bloat” NIST SP 800 52r2 warned against. And the risks to interoperability have played out in practice: Cloudflare IPsec does not yet interoperate with Palo Alto Networks’ RFC 9370–based implementation, because it was launched before draft-ietf-ipsecme-ikev2-mlkem was available.
Fortunately, we now have draft-ietf-ipsecme-ikev2-mlkem that fills in the gaps in RFC 9370, specifying hybrid ML-KEM as one of the key exchange mechanisms that can be operated in parallel with classical Diffie-Hellman. We hope to add Palo Alto Networks to the list of interoperable post-quantum branch connectors as the industry continues to consolidate around draft-ietf-ipsecme-ikev2-mlkem.
But the journey towards interoperable post-quantum IPsec standards is not over yet. While draft-ietf-ipsecme-ikev2-mlkem supports post-quantum encryption, we still need IPsec standards for post-quantum authentication, so that we can stop attacks by quantum adversaries on live systems after Q-Day. Given the shortened timeline for full post-quantum readiness, we hope the IPsec community will continue to focus on interoperable PQC implementations, rather than diverting focus to niche use cases with QKD.
Towards an interoperable post-quantum Internet
At Cloudflare, we’re helping make a secure and post-quantum Internet accessible to everyone, without specialized hardware and at no extra cost to our customers. Post-quantum Cloudflare IPsec is one more step on our path to full post-quantum security by 2029, and we’re doing it in a way that ensures that the Internet remains open and interoperable for years to come.
Google says that it will fully transition to post-quantum cryptography by 2029. I think this is a good move, not because I think we will have a useful quantum computer anywhere near that year, but because crypto-agility is always a good thing.
During Security Week 2025, we launched the industry’s first cloud-nativepost-quantum Secure Web Gateway (SWG) and Zero Trust solution, a major step towards securing enterprise network traffic sent from end user devices to public and private networks.
But this is only part of the equation. To truly secure the future of enterprise networking, you need a complete Secure Access Service Edge (SASE).
Today, we complete the equation: Cloudflare One is the first SASE platform to support modern standards-compliant post-quantum (PQ) encryption in our Secure Web Gateway, and across Zero Trust and Wide Area Network (WAN) use cases. More specifically, Cloudflare One now offers post-quantum hybrid ML-KEM (Module-Lattice-based Key-Encapsulation Mechanism) across all major on-ramps and off-ramps.
To complete the equation, we added support for post-quantum encryption to our Cloudflare IPsec (our cloud-native WAN-as-a-Service) and Cloudflare One Appliance (our physical or virtual WAN appliance that establish Cloudflare IPsec connections). Cloudflare IPsec uses the IPsec protocol to establish encrypted tunnels from a customer’s network to Cloudflare’s global network, while IP Anycast is used to automatically route that tunnel to the nearest Cloudflare data center. Cloudflare IPsec simplifies configuration and provides high availability; if a specific data center becomes unavailable, traffic is automatically rerouted to the closest healthy data center. Cloudflare IPsec runs at the scale of our global network, and supports site-to-site across a WAN as well as outbound connections to the Internet.
Quantum threats are not a “next decade” problem. Here is why our customers are prioritizing post-quantum cryptography (PQC) today:
The deadline is approaching. At the end of 2024, the National Institute of Standards and Technology (NIST) sent a clear signal (that has been echoed by other agencies): the era of classical public-key cryptography is coming to an end. NIST set a 2030 deadline for depreciating RSA and Elliptic Curve Cryptography (ECC) and transitioning to PQC that cannot be broken by powerful quantum computers. Organizations that haven’t begun their migration risk being out of compliance and vulnerable as the deadline nears.
Upgrades have historically been tricky. While 2030 might seem far away, upgrading cryptographic algorithms is notoriously difficult. History has shown us that depreciating cryptography can take decades: we found examples of MD5 causing problems 20 years after it was deprecated. This lack of crypto agility — the ability to easily swap out cryptographic algorithms — is a major bottleneck. By integrating PQ encryption directly into Cloudflare One, our SASE platform, we provide built-in crypto agility, simplifying how organizations offer remote access and site-to-site connectivity.
Data may already be at risk. Finally, “Harvest Now, Decrypt Later” is a present and persistent threat, where attackers harvest sensitive network traffic today and then store it until quantum computers become powerful enough to decrypt it. If your data has a shelf life of more than a few years (e.g. financial information, health data, state secrets) it is already at risk unless it is protected by PQ encryption.
The two migrations on the road to quantum safety: key agreement and digital signatures
Transitioning network traffic to post-quantum cryptography (PQC) requires an overhaul of two cryptographic primitives: key agreement and digital signatures.
Migration 1: Key establishment. Key agreement allows two parties to establish a shared secret over an insecure channel; the shared secret is then used to encrypt network traffic, resulting in post-quantum encryption. The industry has largely converged on ML-KEM (Module-Lattice-based Key-Encapsulation Mechanism) as the standard PQ key agreement protocol.
ML-KEM has been widely adopted for use in TLS, usually deployed alongside classical Elliptic Curve Diffie Hellman (ECDHE), where the key used to encrypt network traffic is derived by mixing the outputs of the ML-KEM and ECDHE key agreements. (This is also known as “hybrid ML-KEM”). Well over 60% of human-generated TLS traffic to Cloudflare’s network is currently protected with hybrid ML-KEM. The transition to hybrid ML-KEM has been successful because it:
stops “harvest-now, decrypt-later” attacks
does not require specialized hardware or specialized physical connectivity between client and server, unlike approaches like Quantum Key Distribution (QKD)
Because ML-KEM runs in parallel with classical ECDHE, there is no reduction in security and compliance as compared to the classical ECDHE approach.
Migration 2: Digital signatures. Meanwhile, digital signatures and certificates protect authenticity, stopping active adversaries from impersonating the server to the client. Unfortunately, PQ signatures are currently larger in size than classical ECC algorithms, which has slowed their adoption. Fortunately, the migration to PQ signatures is less urgent, because PQ signatures are designed to stop active adversaries armed with powerful quantum computers, which are not known to exist yet. Thus, while Cloudflare is actively contributing to the standardization and rollout of PQ digital signatures, the current Cloudflare IPsec upgrade focuses on upgrading key establishment to hybrid ML-KEM.
The U.S. Cybersecurity & Infrastructure Security Agency (CISA) recognized the nature of these two migrations in its January 2026 publication, “Product Categories for Technologies That Use Post-Quantum Cryptography Standards.”
Breaking new ground with IPsec
To achieve a SASE fully protected with post-quantum encryption, we’ve upgraded our Cloudflare IPsec products to support hybrid ML-KEM in the IPsec protocol.
The IPsec community’s journey toward post-quantum cryptography has been very different from that of TLS. TLS is the de facto standard for encrypting public Internet traffic at Layer 4 — e.g. from a browser to a content delivery network (CDN) — so security and vendor interoperability are at the forefront of its design. Meanwhile, IPsec is a Layer 3 protocol that commonly connects devices built by the same vendor (e.g. two routers), so interoperability has historically been less of a concern. With this in mind, let’s take a look at IPsec’s journey into the quantum future.
Pre-Shared Keys? Quantum key distribution?
RFC 8784, published in May 2020, was intended to be the post-quantum update to IPsec Internet Key Exchange v2 (IKEv2), which is used to establish the symmetric keys used to encrypt IPsec network traffic. RFC 8784 implies the use of either long-lived pre-shared keys (PSK) or quantum key distribution (QKD). Neither of these approaches are very palatable.
RFC 8784 proposes mixing a PSK with a key derived from Diffie Hellman Exchange (DHE), essentially running PSK in hybrid with DHE. This approach protects against harvest-now-decrypt-later attackers, but does not offer forward secrecy against quantum adversaries.
Forward secrecy is a standard desideratum of key agreement protocols. It ensures that a system is secure even if the long-lived key is leaked. The PSK approach in RFC 8784 is vulnerable to an harvest-now-decrypt-later adversary that also obtains a copy of a long-lived PSK, and can then decrypt traffic in the future (by breaking the DHE key agreement) once powerful quantum computers become available.
To solve this forward secrecy issue, RFC 8784 can instead be used to mix the key from the classical DHE with a freshly generated key derived from a QKD protocol.
QKD uses quantum mechanics to establish a shared, secret cryptographic key between two parties. Importantly, for QKD to work, the parties must have specialized hardware or be connected by a dedicated physical connection. This is a significant limitation, rendering QKD useless for common Internet use cases like connecting a laptop to a distant server over Wi-Fi. These limitations are also why we never invested in deploying QKD for Cloudflare IPsec. The U.S. National Security Agency (NSA), Germany’s BSI and the UK National Cyber Security Centre have also warned against relying solely on QKD.
But what about interoperability?
RFC 9370 landed in May 2023, specifying the use of hybrid key agreement rather than PSK or QKD. But unlike TLS, which only supports using post-quantum ML-KEM in parallel with classical DHE, this IPsec standard allows using up to seven different key agreements to run at the same time in parallel with classical Diffie Helman. Moreover, it doesn’t specify details about what these key agreements should be, leaving it up to the vendors to choose their algorithms and implementations. Palo Alto Networks, for example, took this seriously and built support for over seven different PQC ciphersuites into its next generation firewall (NGFW), most of which do not interoperate with other vendors and some of which have not yet been standardized by NIST.
Over the years, TLS has gone in the opposite direction, reducing the number of registered ciphersuites from hundreds in TLS 1.2, down to around five in TLS 1.3. This philosophy of reducing “ciphersuite bloat” is also in line with NIST’s SP 800 52 from 2019. The rationale for reducing “ciphersuite bloat” includes:
Improved interoperability across vendors and regions
Lower risk of attacks that exploit downgrades to weak ciphersuites
Lower risk of security problems due to misconfiguration
Lower risk of implementation flaws by reducing the size of the codebase
This is why we didn’t initially build support for RFC 9370.
Standards that are finally on the right track
It’s also why we were excited when the IPsec community put forth draft-ietf-ipsecme-ikev2-mlkem. This Internet-Draft standardizes PQ exchange for IPsec in the same way PQ key exchange has been widely deployed for TLS: hybrid ML-KEM. The new draft fills in the gaps in RFC 9370, by specifying how to run the ML-KEM as the additional key exchange in parallel with classical Diffie Hellman in IKEv2.
Now that this specification is available, we’ve moved forward with supporting post-quantum IPsec in our Cloudflare IPsec products.
Cloudflare IPsec goes post-quantum
Cloudflare IPsec is a WAN Network-as-a-Service solution that replaces legacy private network architectures by connecting data centers, branch offices, and cloud VPCs to Cloudflare’s global IP Anycast network.
With Cloudflare IPsec, Cloudflare’s network acts as the IKEv2 Responder, awaiting connection requests from an IPsec initiator, which is a branch connector device in the customer’s network. Cloudflare IPsec supports IPsec sessions initiated by branch connectors that include our own Cloudflare One Appliance, along with branch connectors from a diverse set of vendors, including Cisco, Juniper, Palo Alto Networks, Fortinet, Aruba and others.
We’ve implemented production hybrid ML-KEM support in the Cloudflare IPsec IKEv2 Responder, as specified in draft-ietf-ipsecme-ikev2-mlkem. The draft requires a first key exchange to run using a classical Diffie Helman key exchange. The derived key is used to encrypt a second key exchange that is run using ML-KEM. Finally, the keys derived by the two exchanges are mixed and the result is used to secure the data plane traffic in IPsec ESP (Encapsulating Security Payload) mode. ESP mode uses symmetric cryptography and is thus already quantum safe without any additional upgrades. We’ve tested our implementation against the IPsec Initiator in the strongswan reference implementation.
You can see the ciphersuite used in the IKEv2 negotiation by viewing the Cloudflare IPsec logs.
We chose to implement hybrid ML-KEM rather than “pure” ML-KEM, i.e. only ML-KEM without DHE running in parallel, for two reasons. First, we’ve used hybrid ML-KEM across all of our other Cloudflare products, since this is the approach adopted across the TLS community. And second, it provides a “belt-and-suspenders” security: ML-KEM provides protection against quantum harvest-now-decrypt-later attacks, while DHE provides a tried-and-true algorithm against non-quantum adversaries.
An invitation for interoperability
The full value of this implementation can be realized only via interoperability. For this reason, we are inviting other vendors that are building out support for IPsec Initiators in their branch connectors per draft-ietf-ipsecme-ikev2-mlkem to test against our Cloudflare IPsec implementation. Cloudflare customers looking to test out interoperability with third-party branch connectors while we are in closed beta can get in touch with us by reaching out to your account team at [email protected]. We plan to GA and build out interoperability with other vendors as more begin to come online with support for draft-ietf-ipsecme-ikev2-mlkem.
Quantum-safe hardware: the Cloudflare One Appliance
Many of our customers purchase their branch connector (hardware or virtualized) from Cloudflare, rather than a third-party vendor. That’s why the Cloudflare One Appliance — our plug-and-play appliance that connects your local network to Cloudflare One — has also been upgraded with post-quantum encryption.
Cloudflare One Appliance does not use IKEv2 for key agreement or session establishment, opting instead to rely on TLS. The appliance periodically initiates a TLS handshake with the Cloudflare edge, shares a symmetric secret over the resulting TLS connection, then injects that symmetric secret into the ESP layer of IPsec, which then encrypts and authenticates the IPsec data plane traffic. This design allowed us to avoid building out IKEv2 Initiator logic, and makes the Connector easier to maintain using our existing TLS libraries.
Thus, upgrading Cloudflare One Appliance to PQ encryption was just a matter of upgrading TLS 1.2 to TLS 1.3 with hybrid ML-KEM — something we’ve done many times on different products at Cloudflare.
How do I turn this on? And what does it cost?
As always, this upgrade to Cloudflare IPsec comes at no extra cost to our customers. Because we believe that a secure and private Internet should be accessible to all, we’re on a mission to include PQC in all our products, without specialized hardware, at no extra cost to our customers and end users.
Customers using the Cloudflare One Appliance obtained this upgrade to PQC in version 2026.2.0 (released 2026-02-11). The upgrade is pushed automatically (with no customer action required) according to each appliance’s configured interrupt window.
For customers using Cloudflare IPsec with another vendor’s branch connector appliance, we will be interoperating with these once more support for draft-ietf-ipsecme-ikev2-mlkem comes online. You can also contact us directly to get access to closed beta and request that we interoperate with a specific vendor’s branch connector by reaching out to your account team at [email protected].
The full picture: post-quantum SASE
The value proposition for a post-quantum SASE is clear: organizations can obtain immediate end-to-end protection for their private network traffic by sending it over tunnels protected by hybrid ML-KEM. This protects traffic from harvest-now-decrypt-later attacks, even if the individual applications in the corporate network are not yet upgraded to PQC.
The diagram above shows how post-quantum hybrid ML-KEM is offered in various Cloudflare One network configurations. It includes the following on-ramps:
Cloudflare IPsec on-ramp (as described in this blog)
The diagram below highlights a sample network configuration that uses the Cloudflare One Client on-ramp to connect a device to a server behind a Cloudflare One Appliance offramp. The end user’s device connects to the Cloudflare network (link 1) using MASQUE with hybrid ML-KEM. The traffic then travels across Cloudflare’s global network over TLS 1.3 with hybrid ML-KEM (link 2). Traffic then leaves the Cloudflare network over a post-quantum Cloudflare IPsec link (link 3) that is terminated at a Cloudflare One Appliance appliance. Finally it connects to a server inside the customer’s environment. Traffic is protected by post-quantum cryptography as it travels over the public Internet, even if the server itself does not support post-quantum cryptography.
Finally, we note that traffic that on-ramps to Cloudflare One and then egresses to the public Internet can also be protected by our post-quantum Cloudflare Gateway, our Secure Web Gateway (SWG). Here’s a diagram showing how the SWG works:
As discussed in an earlier blog post, our SWG can already support hybrid ML-KEM on traffic from SWG to the origin server (as long as the origin supports hybrid ML-KEM), and on traffic from the client to the SWG (if the client supports hybrid ML-KEM, which is the case for most modern browsers). Importantly, any traffic that onramps to the SWG via a device that has Cloudflare One Client installed is still protected with hybrid ML-KEM — even if the web browser itself does not yet support post-quantum cryptography. This is due to the post-quantum MASQUE tunnel that the Cloudflare One Client establishes to Cloudflare’s global network. The same is true of traffic that onramps to the SWG via a post-quantum Cloudflare IPsec tunnel.
Putting it all together, Cloudflare One now offers post-quantum encryption on our TLS, MASQUE and IPsec on-ramp and off-ramps, and for private network traffic, and to traffic that egresses to the public Internet via our SWG.
The future is quantum-safe
By completing the post-quantum SASE equation with Cloudflare IPsec and the Cloudflare One Appliance, we have extended post-quantum encryption across all our major on-ramps and off-ramps. We have intentionally chosen the path of interoperability and simplicity — the hybrid ML-KEM approach that the IETF and NIST have championed, rather than locking our customers into proprietary implementations, “ciphersuite bloat,” or unnecessary hardware upgrades.
This is the promise of Cloudflare One: a SASE platform that is not only faster and more reliable than the legacy architectures it replaces, but one that provides post-quantum encryption. Whether you are securing a remote worker’s browser or a multi-gigabit data center link, you can now do so with the confidence that your data is protected from harvest-now-decrypt-later attacks and other future-looking threats.
You can sign up here to get a full demo of our post-quantum capabilities across the Cloudflare One SASE platform. We are proud to lead the industry into this new era of cryptography, and we invite you to join us in building a scalable, standards-compliant, and post-quantum Internet.
The Business of Secrets: Adventures in Selling Encryption Around the World by Fred Kinch (May 24, 2024)
From the vantage point of today, it’s surreal reading about the commercial cryptography business in the 1970s. Nobody knew anything. The manufacturers didn’t know whether the cryptography they sold was any good. The customers didn’t know whether the crypto they bought was any good. Everyone pretended to know, thought they knew, or knew better than to even try to know.
The Business of Secrets is the self-published memoirs of Fred Kinch. He was founder and vice president of—mostly sales—at a US cryptographic hardware company called Datotek, from company’s founding in 1969 until 1982. It’s mostly a disjointed collection of stories about the difficulties of selling to governments worldwide, along with descriptions of the highs and (mostly) lows of foreign airlines, foreign hotels, and foreign travel in general. But it’s also about encryption.
Datotek sold cryptographic equipment in the era after rotor machines and before modern academic cryptography. The company initially marketed computer-file encryption, but pivoted to link encryption—low-speed data, voice, fax—because that’s what the market wanted.
These were the years where the NSA hired anyone promising in the field, and routinely classified—and thereby blocked—publication of academic mathematics papers of those they didn’t hire. They controlled the fielding of strong cryptography by aggressively using the International Traffic in Arms regulation. Kinch talks about the difficulties in getting an expert license for Datotek’s products; he didn’t know that the only reason he ever got that license was because the NSA was able to break his company’s stuff. He had no idea that his largest competitor, the Swiss company Crypto AG, was owned and controlled by the CIA and its West German equivalent. “Wouldn’t that have made our life easier if we had known that back in the 1970s?” Yes, it would. But no one knew.
Glimmers of the clandestine world peek out of the book. Countries like France ask detailed tech questions, borrow or buy a couple of units for “evaluation,” and then disappear again. Did they break the encryption? Did they just want to see what their adversaries were using? No one at Datotek knew.
Kinch “carried the key generator logic diagrams and schematics” with him—even today, it’s good practice not to rely on their secrecy for security—but the details seem laughably insecure: four linear shift registers of 29, 23, 13, and 7 bits, variable stepping, and a small nonlinear final transformation. The NSA probably used this as a challenge to its new hires. But Datotek didn’t know that, at the time.
Kinch writes: “The strength of the cryptography had to be accepted on trust and only on trust.” Yes, but it’s so, so weird to read about it in practice. Kinch demonstrated the security of his telephone encryptors by hooking a pair of them up and having people listen to the encrypted voice. It’s rather like demonstrating the safety of a food additive by showing that someone doesn’t immediately fall over dead after eating it. (In one absolutely bizarre anecdote, an Argentine sergeant with a “hearing defect” could understand the scrambled analog voice. Datotek fixed its security, but only offered the upgrade to the Argentines, because no one else complained. As I said, no one knew anything.)
In his postscript, he writes that even if the NSA could break Datotek’s products, they were “vastly superior to what [his customers] had used previously.” Given that the previous devices were electromechanical rotor machines, and that his primary competition was a CIA-run operation, he’s probably right. But even today, we know nothing about any other country’s cryptanalytic capabilities during those decades.
A lot of this book has a “you had to be there” vibe. And it’s mostly tone-deaf. There is no real acknowledgment of the human-rights-abusing countries on Datotek’s customer list, and how their products might have assisted those governments. But it’s a fascinating artifact of an era before commercial cryptography went mainstream, before academic cryptography became approved for US classified data, before those of us outside the triple fences of the NSA understood the mathematics of cryptography.
The Internet is in the midst of one of the most complex transitions in its history: the migration to post-quantum (PQ) cryptography. Making a system safe against quantum attackers isn’t just a matter of replacing elliptic curves and RSA with PQ alternatives, such as ML-KEM and ML-DSA. These algorithms have higher costs than their classical counterparts, making them unsuitable as drop-in replacements in many situations.
Nevertheless, we’re making steady progress on the most important systems. As of this writing, about 50% of TLS connections to Cloudflare’s edge are safe against store-now/harvest-later attacks. Quantum safe authentication is further out, as it will require more significant changes to how certificates work. Nevertheless, this year we’ve taken a major step towards making TLS deployable at scale with PQ certificates.
That said, TLS is only the lowest hanging fruit. There are many more ways we have come to rely on cryptography than key exchange and authentication and which aren’t as easy to migrate. In this blog post, we’ll take a look at Anonymous Credentials (ACs).
ACs solve a common privacy dilemma: how to prove a specific fact (for example that one has had a valid driver’s license for more than three years) without over-sharing personal information (like the place of birth)? Such problems are fundamental to a number of use cases, and ACs may provide the foundation we need to make these applications as private as possible.
Just like for TLS, the central question for ACs is whether there are drop-in, PQ replacements for its classical primitives that will work at the scale required, or will it be necessary to re-engineer the application to mitigate the cost of PQ.
We’ll take a stab at answering this question in this post. We’ll focus primarily on an emerging use case for ACs described in a concurrent post: rate-limiting requests from agentic AI platforms and users. This demanding, high-scale use case is the perfect lens through which to evaluate the practical readiness of today’s post-quantum research. We’ll use it as our guiding problem to measure each cryptographic approach.
We’ll first explore the current landscape of classical AC adoption across the tech industry and the public sector. Then, we’ll discuss what cryptographic researchers are currently looking into on the post-quantum side. Finally, we’ll take a look at what it’ll take to bridge the gap between theory and real-world applications.
While anonymous credentials are only seeing their first real-world deployments in recent years, it is critical to start thinking about the post-quantum challenge concurrently. This isn’t a theoretical, too-soon problem given the store-now decrypt-later threat. If we wait for mass adoption before solving post-quantum anonymous credentials, ACs risk being dead on arrival. Fortunately, our survey of the state of the art shows the field is close to a practical solution. Let’s start by reviewing real-world use-cases of ACs.
Real world (classical) anonymous credentials
In 2026, the European Union is set to launch its digital identity wallet, a system that will allow EU citizens, residents and businesses to digitally attest to their personal attributes. This will enable them, for example, to display their driver’s license on their phone or perform ageverification. Cloudflare’s use cases for ACs are a bit different and revolve around keeping our customers secure by, for example, rate limiting bots and humans as we currently do with Privacy Pass. The EU wallet is a massive undertaking in identity provisioning, and our work operates at a massive scale of traffic processing. Both initiatives are working to solve a shared fundamental problem: allowing an entity to prove a specific attribute about themselves without compromising their privacy by revealing more than they have to.
The EU’s goal is a fully mobile, secure, and user-friendly digital ID. The current technical plan is ambitious, as laid out in the Architecture Reference Framework (ARF). It defines the key privacy goals of unlinkability to guarantee that if a user presents attributes multiple times, the recipients cannot link these separate presentations to conclude that they concern the same user. However, currently proposed solutions fail to achieve this. The framework correctly identifies the core problem: attestations contain unique, fixed elements such as hash values, […], public keys, and signatures that colluding entities could store and compare to track individuals.
In its present form, the ARF’s recommendation to mitigate cross-session linkability is limited-time attestations. The framework acknowledges in the text that this would only partially mitigate Relying Party linkability. An alternative proposal that would mitigate linkability risks are single-use credentials. They are not considered at the moment due to complexity and management overhead. The framework therefore leans on organisational and enforcement measures to deter collusion instead of providing a stronger guarantee backed by cryptography.
This reliance on trust assumptions could become problematic, especially in the sensitive context of digital identity. When asked for feedback, cryptographic researchers agree that the proper solution would be to adopt anonymous credentials. However, this solution presents a long-term challenge. Well-studied methods for anonymous credentials, such as those based on BBS signatures, are vulnerable to quantum computers. While some anonymousschemes are PQ-unlinkable, meaning that user privacy is preserved even when cryptographically relevant quantum computers exist, new credentials could be forged. This may be an attractive target for, say, a nation state actor.
New cryptography also faces deployment challenges: in the EU, only approved cryptographic primitives, as listed in the SOG-IS catalogue, can be used. At the time of writing, this catalogue is limited to established algorithms such as RSA or ECDSA. But when it comes to post-quantum cryptography, SOG-IS is leaving the problem wide open.
The wallet’s first deployment will not be quantum-secure. However, with the transition to post-quantum algorithms being ahead of us, as soon as 2030 for high-risk use cases per the EU roadmap, research in a post-quantum compatible alternative for anonymous credentials is critical. This will encompassstandardizing more cryptography.
Finally, ongoing efforts at the Internet Engineering Task Force (IETF)aimto build a more private Internet by standardizing advanced cryptographic techniques. Active individual drafts (i.e., not yet adopted by a working group), such as Longfellow and Anonymous Credit Tokens (ACT), and adopted drafts like Anonymous Rate-limited Credentials (ARC), propose more flexible multi-show anonymous credentials that incorporate developments over the last several years. At IETF 117 in 2023, post-quantum anonymous credentials and deployable generic anonymous credentials were presented as a research opportunity. Check out our post on rate limiting agents for details.
Before we get into the state-of-the-art for PQ, allow us to try to crystalize a set of requirements for real world applications.
Requirements
Given the diversity of use cases, adoption of ACs will be made easier by the fact that they can be built from a handful of powerful primitives. (More on this in our concurrent post.) As we’ll see in the next section, we don’t yet have drop-in, PQ alternatives for these kinds of primitives. The “building blocks” of PQ ACs are likely to look quite different, and we’re going to know something about what we’re building towards.
For our purposes, we can think of an anonymous credential as a kind of fancy blind signature. What’s that you ask? A blind signature scheme has two phases: issuance, in which the server signs a message chosen by the client; and presentation, in which the client reveals the message and the signature to the server. The scheme should be unlinkable in the sense that the server can’t link any message and signature to the run of the issuance protocol in which it was produced. It should also be unforgeable in the sense that no client can produce a valid signature without interacting with the server.
The key difference between ACs and blind signatures is that, during presentation of an AC, the client only presents part of the message in plaintext; the rest of the message is kept secret. Typically, the message has three components:
Private state, such as a counter that, for example, keeps track of the number of times the credential was presented. The client would prove to the server that the state is “valid”, for example, a counter with value $0 \leq C \leq N$, without revealing $C$. In many situations, it’s desirable to allow the server to update this state upon successful presentation, for example, by decrementing the counter. In the context of rate limiting, this is the number of how many requests are left for a credential.
A random value called the nullifier that is revealed to the server during presentation. In rate-limiting, the nullifier prevents a user from spending a credential with a given state more than once.
Public attributes known to both the client and server that bind the AC to some application context. For example, this might represent the window of time in which the credential is valid (without revealing the exact time it was issued).
Such ACs are well-suited for rate limiting requests made by the client. Here the idea is to prevent the client from making more than some maximum number of requests during the credential’s lifetime. For example, if the presentation limit is 1,000 and the validity window is one hour, then the clients can make up to 0.27 requests/second on average before it gets throttled.
It’s usually desirable to enforce rate limits on a per-origin basis. This means that if the presentation limit is 1,000, then the client can make at most 1,000 requests to any website that can verify the credential. Moreover, it can do so safely, i.e., without breaking unlinkability across these sites.
The current generation of ACs being considered for standardization at IETF are only privately verifiable, meaning the server issuing the credential (the issuer) must share a private key with the server verifying the credential (the origin). This will be sufficient for some deployment scenarios, but many will require public verifiability, where the origin only needs the issuer’s public key. This is possible with BBS-based credentials, for example.
Finally, let us say a few words about round complexity. An AC is round optimal if issuance and presentation both complete in a single HTTP request and response. In our survey of PQ ACs, we found a number of papers that discovered neat tricks that reduce bandwidth (the total number of bits transferred between the client and server) at the cost of additional rounds. However, for use cases like ours, round optimality is an absolute necessity, especially for presentation. Not only do multiple rounds have a high impact on latency, they also make the implementation far more complex.
Within these constraints, our goal is to develop PQ ACs that have as low communication cost (i.e., bandwidth consumption) and runtime as possible in the context of rate-limiting.
“Ideal world” (PQ) anonymous credentials
The academic community has produced a number of promising post-quantum ACs. In our survey of the state of the art, we evaluated several leading schemes, scoring them on their underlying primitives and performance to determine which are truly ready for the Internet. To understand the challenges, it is essential to first grasp the cryptographic building blocks used in ACs today. We’ll now discuss some of the core concepts that frequently appear in the field.
Relevant cryptographic paradigms
Zero-knowledge proofs
Zero-knowledge proofs (ZKPs) are a cryptographic protocol that allows a prover to convince a verifier that a statement is true without revealing the secret information, or witness. ZKPs play a central role in ACs: they allow proving statements of the secret part of the credential’s state without revealing the state itself. This is achieved by transforming the statement into a mathematical representation, such as a set of polynomial equations over a finite field. The prover then generates a proof by performing complex operations on this representation, which can only be completed correctly if they possess the valid witness.
General-purpose ZKP systems, like Scalable Transparent Arguments of Knowledge (STARKs), can prove the integrity of any computation up to a certain size. In a STARK-based system, the computational trace is represented as a set of polynomials. The prover then constructs a proof by evaluating these polynomials and committing to them using cryptographic hash functions. The verifier can then perform a quick probabilistic check on this proof to confirm that the original computation was executed correctly. Since the proof itself is just a collection of hashes and sampled polynomial values, it is secure against quantum computers, providing a statistically sound guarantee that the claimed result is valid.
Cut-and-Choose
Cut-and-choose is a cryptographic technique designed to ensure a prover’s honest behaviour by having a verifier check a random subset of their work. The prover first commits to multiple instances of a computation, after which the verifier randomly chooses a portion to be cut open by revealing the underlying secrets for inspection. If this revealed subset is correct, the verifier gains high statistical confidence that the remaining, un-opened instances are also correct.
This technique is important because while it is a generic tool used to build protocols secure against malicious adversaries, it also serves as a crucial case study. Its security is not trivial; for example, practical attacks on cut-and-choose schemes built with (post-quantum) homomorphic encryption have succeeded by attacking the algebraic structure of the encoding, not the encryption itself. This highlights that even generic constructions must be carefully analyzed in their specific implementation to prevent subtle vulnerabilities and information leaks.
Sigma Protocols
Sigma protocols follow a more structured approach that does not require us to throw away any computations. The three-move protocol starts with a commitment phase where the prover generates some randomness, which is added to the input to generate the commitment, and sends the commitment to the verifier. Then, the verifier challenges the prover with an unpredictable challenge. To finish the proof, the prover provides a response in which they combine the initial randomness with the verifier’s challenge in a way that is only possible if the secret value, such as the solution to a discrete logarithm problem, is known.
Depiction of a Sigma protocol flow, where the prover commits to their witness $w$, the verifier challenges the prover to prove knowledge about $w$, and the prover responds with a mathematical statement that the verifier can either accept or reject.
In practice, the prover and verifier don’t run this interactive protocol. Instead, they make it non-interactive using a technique known as the Fiat-Shamir transformation. The idea is that the prover generates the challenge itself, by deriving it from its own commitment. It may sound a bit odd, but it works quite well. In fact, it’s the basis of signatures like ECDSA and even PQ signatures like ML-DSA.
MPC in the head
Multi-party computation (MPC) is a cryptographic tool that allows multiple parties to jointly compute a function over their inputs without revealing their individual inputs to the other parties. MPC in the Head (MPCitH) is a technique to generate zero-knowledge proofs by simulating a multi-party protocol in the head of the prover.
The prover simulates the state and communication for each virtual party, commits to these simulations, and shows the commitments to the verifier. The verifier then challenges the prover to open a subset of these virtual parties. Since MPC protocols are secure even if a minority of parties are dishonest, revealing this subset doesn’t leak the secret, yet it convinces the verifier that the overall computation was correct.
This paradigm is particularly useful to us because it’s a flexible way to build post-quantum secure ZKPs. MPCitH constructions build their security from symmetric-key primitives (like hash functions). This approach is also transparent, requiring no trusted setup. While STARKs share these post-quantum and transparent properties, MPCitH often offers faster prover times for many computations. Its primary trade-off, however, is that its proofs scale linearly with the size of the circuit to prove, while STARKs are succinct, meaning their proof size grows much slower.
Rejection sampling
When a randomness source is biased or outputs numbers outside the desired range, rejection sampling can correct the distribution. For example, imagine you need a random number between 1 and 10, but your computer only gives you random numbers between 0 and 255. (Indeed, this is the case!) The rejection sampling algorithm calls the RNG until it outputs a number below 11 and above 0:
Calling the generator over and over again may seem a bit wasteful. An efficient implementation can be realized with an eXtendable Output Function (XOF). A XOF takes an input, for example a seed, and computes an arbitrarily-long output. An example is the SHAKE family (part of the SHA3 standard), and the recently proposed round-reduced version of SHAKE called TurboSHAKE.
Let’s imagine you want to have three numbers between 1 and 10. Instead of calling the XOF over and over, you can also ask the XOF for several bytes of output. Since each byte has a probability of 3.52% to be in range, asking the XOF for 174 bytes is enough to have a greater than 99% chance of finding at least three usable numbers. In fact, we can be even smarter than this: 10 fits in four bits, so we can split the output bytes into lower and higher nibbles. The probability of a nibble being in the desired range is now 56.4%:
Rejection sampling by batching queries.
Rejection sampling is a part of many cryptographic primitives, including many we’ll discuss in the schemes we look at below.
Building post-quantum ACs
Classical anonymous credentials (ACs), such as ARC and ACT, are built from algebraic groups- specifically, elliptic curves, which are very efficient. Their security relies on the assumption that certain mathematical problems over these groups are computationally hard. The premise of post-quantum cryptography, however, is that quantum computers can solve these supposedly hard problems. The most intuitive solution is to replace elliptic curves with a post-quantum alternative. In fact, cryptographers have been working on a replacement for a number of years: CSIDH.
This raises the key question: can we simply adapt a scheme like ARC by replacing its elliptic curves with CSIDH? The short answer is no, due to a critical roadblock in constructing the necessary zero-knowledge proofs. While we can, in theory, build the required Sigma protocols or MPC-in-the-Head (MPCitH) proofs from CSIDH, they have a prerequisite that makes them unusable in practice: they require a trusted setup to ensure the prover cannot cheat. This requirement is a non-starter, as no algorithm for performing a trusted setup in CSIDH exists. The trusted setup for sigma protocols can be replaced by a combination of generic techniques from multi-party computation and cut-and-choose protocols, but that adds significant computation cost to the already computationally expensive isogeny operations.
This specific difficulty highlights a more general principle. The high efficiency of classical credentials like ARC is deeply tied to the rich algebraic structure of elliptic curves. Swapping this component for a post-quantum alternative, or moving to generic constructions, fundamentally alters the design and its trade-offs. We must therefore accept that post-quantum anonymous credentials cannot be a simple “lift-and-shift” of today’s schemes. They will require new designs built from different cryptographic primitives, such as lattices or hash functions.
Prefabricated schemes from generic approaches
At Cloudflare, we explored a post-quantum privacy pass construction in 2023 that closely resembles the functionality needed for anonymous credentials. The main result is a generic construction that composes separate, quantum-secure building blocks: a digital signature scheme and a general-purpose ZKP system:
The figure shows a cryptographic protocol divided into two main phases: (1.) Issuance: The user commits to a message (without revealing it) and sends the commitment to the server. The server signs the commitment and returns this signed commitment, which serves as a token. The user verifies the server’s signature. (2.) Redemption: To use the token, the user presents it and constructs a proof. This proof demonstrates they have a valid signature on the commitment and opens the commitment to reveal the original message. If the server validates the proof, the user and server continue (e.g., to access a rate-limited origin).
The main appeal of this modular design is its flexibility. The experimental implementation uses a modified version of the signature ML-DSA signatures and STARKs, but the components can be easily swapped out. The design provides strong, composable security guarantees derived directly from the underlying parts. A significant speedup for the construction came from replacing the hash function SHA3 in ML-DSA with the zero-knowledge friendly Poseidon.
However, the modularity of our post-quantum Privacy Pass construction incurs a significant performance overhead demonstrated in a clear trade-off between proof generation time and size: a fast 300 ms proof generation requires a large 173 kB signature, while a 4.8s proof generation time cuts the size of the signature nearly in half. A balanced parameter set, which serves as a good benchmark for any dedicated solution to beat, took 660 ms to sign and resulted in a 112 kB signature. The implementation is currently a proof of concept, with perhaps some room for optimization. Alternatively, a different signature like FN-DSA could offer speed improvements: while its issuance is more complex, its verification is far more straightforward, boiling down to a simple hash-to-lattice computation and a norm check.
However, while this construction gives a functional baseline, these figures highlight the performance limitations for a real-time rate limiting system, where every millisecond counts. The 660 ms signing time strongly motivates the development of dedicated cryptographic constructions that trade some of the modularity for performance.
Solid structure: Lattices
Lattices are a natural starting point when discussing potential post-quantum AC candidates. NIST standardized ML-DSA and ML-KEM as signature and KEM algorithms, both of which are based on lattices. So, are lattices the answer to post-quantum anonymous credentials?
The answer is a bit nuanced. While explicit anonymous credential schemes from lattices exist, they have shortcomings that prevent real-world deployment: for example, a recent scheme sacrifices round-optimality for smaller communication size, which is unacceptable for a service like Privacy Pass where every second counts. Given that our RTT is 100ms or less for the majority of users, each extra communication round adds tangible latency especially for those on slower Internet connections. When the final credential size is still over 100 kB, the trade-offs are hard to justify. So, our search continues. We expand our horizon by looking into blind signatures and whether we can adapt them for anonymous credentials.
Two-step approach: Hash-and-sign
A prominent paradigm in lattice-based signatures is the hash-and-sign construction. Here, the message is first hashed to a point in the lattice. Then, the signer uses their secret key, a lattice trapdoor, to generate a vector that, when multiplied with the private key, evaluates to the hashed point in the lattice. This is the core mechanism behind signature schemes like FN-DSA.
Adapting hash-and-sign for blind signatures is tricky, since the signer may not learn the message. This introduces a significant security challenge: If the user can request signatures on arbitrary points, they can mount an attack to extract the trapdoor by repeatedly requesting signatures for carefully chosen arbitrary points. These points can be used to reconstruct a short basis, which is equivalent to a key recovery.
The standard defense against this attack is to require the user to prove in zero-knowledge that the point they are asking to be signed is the blinded output of the specified hash function. However, proving hash preimages leads to the same problem as in the generic post-quantum privacy pass paper: proving a conventional hash function (like SHA3) inside a ZKP is computationally expensive and has a large communication complexity.
This difficult trade-off is at the heart of recent academic work. The state-of-the-art paper presents two lattice-based blind signature schemes with small signature sizes of 22 KB for a signature and 48 kB for a privately-verifiable protocol that may be more useful in a setting like anonymous credential. However, this focus on the final signature size comes at the cost of an impractical issuance. The user must provide ZKPs for the correct hash and lattice relations that, by the paper’s own analysis, can add to several hundred kilobytes and take 20 seconds to generate and 10 seconds to verify.
While these results are valuable for advancing the field, this trade-off is a significant barrier for any large-scale, practical system. For our use case, a protocol that increases the final signature size moderately in exchange for a more efficient and lightweight issuance process would be a more suitable and promising direction.
Best of two signatures: Hash-and-sign with aborts
A promising technique for blind signatures combines the hash-and-sign paradigm with Fiat-Shamir with aborts, a method that relies on rejection sampling signatures. In this approach, the signer repeatedly attempts to generate a signature and aborts any result that may leak information about the secret key. This process ensures the final signature is statistically independent of the key and is used in modern signatures like ML-DSA. The Phoenix signature scheme uses hash-and-sign with aborts, where a message is first hashed into the lattice and signed, with rejection sampling employed to break the dependency between the signature and the private key.
Building on this foundation is an anonymous credential scheme for hash-and-sign with aborts. The main improvement over hash-and-sign anonymous credentials is that, instead of proving the validity of a hash, the user commits to their attributes, which avoids costly zero-knowledge proofs.
The scheme is fully implemented and credentials with attribute proofs just under 80 KB and signatures under 7 kB. The scheme takes less than 400 ms for issuance and 500 ms for showing the credential. The protocol also has a lot of features necessary for anonymous credentials, allowing users to prove relations between attributes and request pseudonyms for different instances.
This research presents a compelling step towards real-world deployability by combining state-of-the-art techniques to achieve a much healthier balance between performance and security. While the underlying mathematics are a bit more complex, the scheme is fully implemented and with a proof of knowledge of a signature at 40 kB and a prover time under a second, the scheme stands out as a great contender. However, for practical deployment, these figures would likely need a significant speedup to be usable in real-time systems. An improvement seems plausible, given recent advances in lattice samplers. Though the exact scale we can achieve is unclear. Still, we think it would be worthwhile to nudge the underlying design paradigm a little closer to our use cases.
Do it yourself: MPC-in-the-head
While the lattice-based hash-and-sign with aborts scheme provides one path to post-quantum signatures, an alternative approach is emerging from the MPCitH variant VOLE-in-the-Head (VOLEitH).
This scheme builds on Vector Oblivious Linear Evaluation (VOLE), an interactive protocol where one party’s input vector is processed with another’s secret value delta, creating a correlation. This VOLE correlation is used as a cryptographic commitment to the prover’s input. The system provides a zero-knowledge proof because the prover is bound by this correlation and cannot forge a solution without knowing the secret delta. The verifier, in turn, just has to verify that the final equation holds when the commitment is opened. This system is linearly homomorphic, which means that two commitments can be combined. This property is ideal for the commit-and-prove paradigm, where the prover first commits to the witnesses and then proves the validity of the circuit gate by gate. The primary trade-off is that the proofs are linear in the size of the circuit, but they offer substantially better runtimes. We also use linear-sized proofs for ARC and ACT.
Example of evaluating a circuit gate by first committing to each wire and then proving the composition. This is easy for linear gates.
This commit-and-prove approach allows VOLEitH to efficiently prove the evaluation of symmetric ciphers, which are quantum-resistant. The transformation to a non-interactive protocol follows the standard MPCitH method: the prover commits to all secret values, a challenge is used to select a subset to reveal, and the prover proves consistency.
Efficient implementations operate over two mathematical fields (binary and prime) simultaneously, allowing these ZK circuits to handle both arithmetic and bitwise functions (like XORs) efficiently. Based on this foundation, a recent talk teased the potential for blind signatures from the multivariate quadratic signature scheme MAYO with sizes of just 7.5 kB and signing/verification times under 50 ms.
The VOLEitH approach, as a general-purpose solution system, represents a promising new direction for performant constructions. There are a numberofcompetingin-the-head schemes in the NIST competition for additional signature schemes, including one based on VOLEitH. The current VOLEitH literature focuses on high-performance digital signatures, and an explicit construction for a full anonymous credential system has not yet been proposed. This means that features standard to ACs, such as multi-show unlinkability or the ability to prove relations between attributes, are not yet part of the design, whereas they are explicitly supported by the lattice construction. However, the preliminary results show great potential for performance, and it will be interesting to see the continued cryptanalysis and feature development from this line of VOLEitH in the area of anonymous credentials, especially since the general-purpose construction allows adding features easily.
Medium: promising research direction, no full solution available so far
Closing the gap
My (that is Lena’s) internship focused on a critical question: what should we look at next to build ACs for the Internet? For us, “the right direction” means developing protocols that can be integrated with real world applications, and developed collaboratively at the IETF. To make these a reality, we need researchers to look beyond blind signatures; we need a complete privacy-preserving protocol that combines blind signatures with efficient zero-knowledge proofs and properties like multi-show credentials that have an internal state. The issuance should also be sublinear in communication size with the number of presentations.
So, with the transition to post-quantum cryptography on the horizon, what are our thoughts on the current IETF proposals? A 2022 NIST presentation on the current state of anonymous credentials states that efficient post-quantum secure solutions are basically non-existent. We argue that the last three years show nice developments in lattices and MPCitH anonymous credentials, but efficient post-quantum protocols still need work. Moving protocols into a post-quantum world isn’t just a matter of swapping out old algorithms for new ones. A common approach on constructing post-quantum versions of classical protocols is swapping out the building blocks for their quantum-secure counterpart.
We believe this approach is essential, but not forward-looking. In addition to identifying how modern concerns can be accommodated on old cryptographic designs, we should be building new, post-quantum native protocols.
For ARC, the conceptual path to a post-quantum construction seems relatively straightforward. The underlying cryptography follows a similar structure as the lattice-based anonymous credentials, or, when accepting a protocol with fewer features, the generic post-quantum privacy-pass construction. However, we need to support per-origin rate-limiting, which allows us to transform a token at an origin without leaking us being able to link the redemption to redemptions at other origins, a feature that none of the post-quantum anonymous credential protocols or blind signatures support. Also, ARC is sublinear in communication size with respect to the number of tokens issued, which so far only the hash-and-sign with abort lattices achieve, although the notion of “limited shows” is not present in the current proposal. In addition, it would be great to gauge efficient implementations, especially for blind signatures, as well as looking into efficient zero-knowledge proofs.
For ACT, we need the protocols for ARC and an additional state. Even for the simplest counter, we need the ability to homomorphically subtract from that balance within the credential itself. This is a much more complex cryptographic requirement. It would also be interesting to see a post-quantum double-spend prevention that enforces the sequential nature of ACT.
Working on ACs and other privacy-preserving cryptography inevitably leads to a major bottleneck: efficient zero-knowledge proofs, or to be more exact, efficiently proving hash function evaluations. In a ZK circuit, multiplications are expensive. Each wire in the circuit that performs a multiplication requires a cryptographic commitment, which adds communication overhead. In contrast, other operations like XOR can be virtually “free.” This makes a huge difference in performance. For example, SHAKE (the primitive used in ML-DSA) can be orders of magnitude slower than arithmetization-friendly hash functions inside a ZKP. This is why researchers and implementers are already using Poseidon or Poseidon2 to make their protocols faster.
Currently, Ethereum is seriously considering migrating Ethereum to the Poseidon hash and calls for cryptanalysis, but there is no indication of standardization. This is a problem: papers increasingly use different instantiations of Poseidon to fit their use-case, and there aremoreandmorezero–knowledgefriendlyhashfunctionscomingout, tailored to different use-cases. We would like to see at least one XOF and one hash each for a prime field and for a binary field, ideally with some security levels. And also, is Poseidon the best or just the most well-known ZK friendly cipher? Is it always secure against quantum computers (like we believe AES to be), and are there other attacks like the recentattacks on round-reduced versions?
Looking at algebra and zero-knowledge brings us to a fundamental debate in modern cryptography. Imagine a line representing the spectrum of research: On one end, you have protocols built on very well-analyzed standard assumptions like the SIS problem on lattices or the collision resistance of SHA3. On the other end, you have protocols that gain massive efficiency by using more algebraic structure, which in turn relies on newer, stronger cryptographic assumptions. Breaking novel hash functions is somewhere in the middle.
The answer for the Internet can’t just be to relent and stay at the left end of our graph to be safe. For the ecosystem to move forward, we need to have confidence in both. We need more research to validate the security of ZK-friendly primitives like Poseidon, and we need more scrutiny on the stronger assumptions that enable efficient algebraic methods.
Conclusion
As we’ve explored, the cryptographic properties that make classical ACs efficient, particularly the rich structure of elliptic curves, do not have direct post-quantum equivalents. Our survey of the state of the art from generic compositions using STARKs, to various lattice-based schemes, and promising new directions like MPC-in-the-head, reveals a field full of potential but with no clear winner. The trade-offs between communication cost, computational cost, and protocol rounds remain a significant barrier to practical, large-scale deployment, especially in comparison to elliptic curve constructions.
To bridge this gap, we must move beyond simply building post-quantum blind signatures. We challenge our colleagues in academia and industry to develop complete, post-quantum native protocols that address real-world needs. This includes supporting essential features like the per-origin rate-limiting required for ARC or the complex stateful credentials needed for ACT.
A critical bottleneck for all these approaches is the lack of efficient, standardized, and well-analyzed zero-knowledge-friendly hash functions. We need to research zero-knowledge friendly primitives and build industry-wide confidence to enable efficient post-quantum privacy.
If you’re working on these problems, or you have experience in the management and deployment of classical credentials, now is the time to engage. The world is rapidly adopting credentials for everything from digital identity to bot management, and it is our collective responsibility to ensure these systems are private and secure for a post-quantum future. We can tell for certain that there are more discussions to be had, and if you’re interested in helping to build this more secure and private digital world, we’re hiring 1,111 interns over the course of next year, and have open positions!
Ultimately, the architects settled on a creative solution. Rather than bolt KEM onto the existing double ratchet, they allowed it to remain more or less the same as it had been. Then they used the new quantum-safe ratchet to implement a parallel secure messaging system.
Now, when the protocol encrypts a message, it sources encryption keys from both the classic Double Ratchet and the new ratchet. It then mixes the two keys together (using a cryptographic key derivation function) to get a new encryption key that has all of the security of the classical Double Ratchet but now has quantum security, too.
The Signal engineers have given this third ratchet the formal name: Sparse Post Quantum Ratchet, or SPQR for short. The third ratchet was designed in collaboration with PQShield, AIST, and New York University. The developers presented the erasure-code-based chunking and the high-level Triple Ratchet design at the Eurocrypt 2025 conference. At the Usenix 25 conference, they discussed the six options they considered for adding quantum-safe forward secrecy and post-compromise security and why SPQR and one other stood out. Presentations at the NIST PQC Standardization Conference and the Cryptographic Applications Workshop explain the details of chunking, the design challenges, and how the protocol had to be adapted to use the standardized ML-KEM.
Jacomme further observed:
The final thing interesting for the triple ratchet is that it nicely combines the best of both worlds. Between two users, you have a classical DH-based ratchet going on one side, and fully independently, a KEM-based ratchet is going on. Then, whenever you need to encrypt something, you get a key from both, and mix it up to get the actual encryption key. So, even if one ratchet is fully broken, be it because there is now a quantum computer, or because somebody manages to break either elliptic curves or ML-KEM, or because the implementation of one is flawed, or…, the Signal message will still be protected by the second ratchet. In a sense, this update can be seen, of course simplifying, as doubling the security of the ratchet part of Signal, and is a cool thing even for people that don’t care about quantum computers.
The world is in a race to build its first quantum computer capable of solving practical problems not feasible on even the largest conventional supercomputers. While the quantum computing paradigm promises many benefits, it also threatens the security of the Internet by breaking much of the cryptography we have come to rely on.
To mitigate this threat, Cloudflare is helping to migrate the Internet to Post-Quantum (PQ) cryptography. Today, about 50% of traffic to Cloudflare’s edge network is protected against the most urgent threat: an attacker who can intercept and store encrypted traffic today and then decrypt it in the future with the help of a quantum computer. This is referred to as the harvest now, decrypt laterthreat.
However, this is just one of the threats we need to address. A quantum computer can also be used to crack a server’s TLS certificate, allowing an attacker to impersonate the server to unsuspecting clients. The good news is that we already have PQ algorithms we can use for quantum-safe authentication. The bad news is that adoption of these algorithms in TLS will require significant changes to one of the most complex and security-critical systems on the Internet: the Web Public-Key Infrastructure (WebPKI).
The central problem is the sheer size of these new algorithms: signatures for ML-DSA-44, one of the most performant PQ algorithms standardized by NIST, are 2,420 bytes long, compared to just 64 bytes for ECDSA-P256, the most popular non-PQ signature in use today; and its public keys are 1,312 bytes long, compared to just 64 bytes for ECDSA. That’s a roughly 20-fold increase in size. Worse yet, the average TLS handshake includes a number of public keys and signatures, adding up to 10s of kilobytes of overhead per handshake. This is enough to have a noticeable impact on the performance of TLS.
That makes drop-in PQ certificates a tough sell to enable today: they don’t bring any security benefit before Q-day — the day a cryptographically relevant quantum computer arrives — but they do degrade performance. We could sit and wait until Q-day is a year away, but that’s playing with fire. Migrations always take longer than expected, and by waiting we risk the security and privacy of the Internet, which is dear to us.
It’s clear that we must find a way to make post-quantum certificates cheap enough to deploy today by default for everyone — not just those that can afford it. In this post, we’ll introduce you to the plan we’ve brought together with industry partners to the IETF to redesign the WebPKI in order to allow a smooth transition to PQ authentication with no performance impact (and perhaps a performance improvement!). We’ll provide an overview of one concrete proposal, called Merkle Tree Certificates (MTCs), whose goal is to whittle down the number of public keys and signatures in the TLS handshake to the bare minimum required.
But talk is cheap. We knowfromexperience that, as with any change to the Internet, it’s crucial to test early and often. Today we’re announcing our intent to deploy MTCs on an experimental basis in collaboration with Chrome Security. In this post, we’ll describe the scope of this experiment, what we hope to learn from it, and how we’ll make sure it’s done safely.
The WebPKI today — an old system with many patches
Why does the TLS handshake have so many public keys and signatures?
Let’s start with Cryptography 101. When your browser connects to a website, it asks the server to authenticate itself to make sure it’s talking to the real server and not an impersonator. This is usually achieved with a cryptographic primitive known as a digital signature scheme (e.g., ECDSA or ML-DSA). In TLS, the server signs the messages exchanged between the client and server using its secret key, and the client verifies the signature using the server’s public key. In this way, the server confirms to the client that they’ve had the same conversation, since only the server could have produced a valid signature.
If the client already knows the server’s public key, then only 1 signature is required to authenticate the server. In practice, however, this is not really an option. The web today is made up of around a billion TLS servers, so it would be unrealistic to provision every client with the public key of every server. What’s more, the set of public keys will change over time as new servers come online and existing ones rotate their keys, so we would need some way of pushing these changes to clients.
This scaling problem is at the heart of the design of all PKIs.
Trust is transitive
Instead of expecting the client to know the server’s public key in advance, the server might just send its public key during the TLS handshake. But how does the client know that the public key actually belongs to the server? This is the job of a certificate.
A certificate binds a public key to the identity of the server — usually its DNS name, e.g., cloudflareresearch.com. The certificate is signed by a Certification Authority (CA) whose public key is known to the client. In addition to verifying the server’s handshake signature, the client verifies the signature of this certificate. This establishes a chain of trust: by accepting the certificate, the client is trusting that the CA verified that the public key actually belongs to the server with that identity.
Clients are typically configured to trust many CAs and must be provisioned with a public key for each. Things are much easier however, since there are only 100s of CAs instead of billions. In addition, new certificates can be created without having to update clients.
These efficiencies come at a relatively low cost: for those counting at home, that’s +1 signature and +1 public key, for a total of 2 signatures and 1 public key per TLS handshake.
That’s not the end of the story, however. As the WebPKI has evolved, so have these chains of trust grown a bit longer. These days it’s common for a chain to consist of two or more certificates rather than just one. This is because CAs sometimes need to rotatetheir keys, just as servers do. But before they can start using the new key, they must distribute the corresponding public key to clients. This takes time, since it requires billions of clients to update their trust stores. To bridge the gap, the CA will sometimes use the old key to issue a certificate for the new one and append this certificate to the end of the chain.
That’s +1 signature and +1 public key, which brings us to 3 signatures and 2 public keys. And we still have a little ways to go.
Trust but verify
The main job of a CA is to verify that a server has control over the domain for which it’s requesting a certificate. This process has evolved over the years from a high-touch, CA-specific process to a standardized, mostly automated process used for issuing most certificates on the web. (Not all CAs fully support automation, however.) This evolution is marked by a number of security incidents in which a certificate was mis-issued to a party other than the server, allowing that party to impersonate the server to any client that trusts the CA.
Automation helps, but attacks are still possible, and mistakes are almost inevitable. Earlier this year, several certificates for Cloudflare’s encrypted 1.1.1.1 resolver were issued without our involvement or authorization. This apparently occurred by accident, but it nonetheless put users of 1.1.1.1 at risk. (The mis-issued certificates have since been revoked.)
Ensuring mis-issuance is detectable is the job of the Certificate Transparency (CT) ecosystem. The basic idea is that each certificate issued by a CA gets added to a public log. Servers can audit these logs for certificates issued in their name. If ever a certificate is issued that they didn’t request itself, the server operator can prove the issuance happened, and the PKI ecosystem can take action to prevent the certificate from being trusted by clients.
Major browsers, including Firefox and Chrome and its derivatives, require certificates to be logged before they can be trusted. For example, Chrome, Safari, and Firefox will only accept the server’s certificate if it appears in at least two logs the browser is configured to trust. This policy is easy to state, but tricky to implement in practice:
Operating a CT log has historically been fairly expensive. Logs ingest billions of certificates over their lifetimes: when an incident happens, or even just under high load, it can take some time for a log to make a new entry available for auditors.
Clients can’t really audit logs themselves, since this would expose their browsing history (i.e., the servers they wanted to connect to) to the log operators.
The solution to both problems is to include a signature from the CT log along with the certificate. The signature is produced immediately in response to a request to log a certificate, and attests to the log’s intent to include the certificate in the log within 24 hours.
Per browser policy, certificate transparency adds +2 signatures to the TLS handshake, one for each log. This brings us to a total of 5 signatures and 2 public keys in a typical handshake on the public web.
The future WebPKI
The WebPKI is a living, breathing, and highly distributed system. We’ve had to patch it a number of times over the years to keep it going, but on balance it has served our needs quite well — until now.
Previously, whenever we needed to update something in the WebPKI, we would tack on another signature. This strategy has worked because conventional cryptography is so cheap. But 5 signatures and 2 public keys on average for each TLS handshake is simply too much to cope with for the larger PQ signatures that are coming.
The good news is that by moving what we already have around in clever ways, we can drastically reduce the number of signatures we need.
Crash course on Merkle Tree Certificates
Merkle Tree Certificates (MTCs) is a proposal for the next generation of the WebPKI that we are implementing and plan to deploy on an experimental basis. Its key features are as follows:
All the information a client needs to validate a Merkle Tree Certificate can be disseminated out-of-band. If the client is sufficiently up-to-date, then the TLS handshake needs just 1 signature, 1 public key, and 1 Merkle tree inclusion proof. This is quite small, even if we use post-quantum algorithms.
The MTC specification makes certificate transparency a first class feature of the PKI by having each CA run its own log of exactly the certificates they issue.
Let’s poke our head under the hood a little. Below we have an MTC generated by one of our internal tests. This would be transmitted from the server to the client in the TLS handshake:
Looks like your average PEM encoded certificate. Let’s decode it and look at the parameters:
$ openssl x509 -in merkle-tree-cert.pem -noout -text
Certificate:
    Data:
        Version: 3 (0x2)
        Serial Number: 531 (0x213)
        Signature Algorithm: 1.3.6.1.4.1.44363.47.0
        Issuer: 1.3.6.1.4.1.44363.47.1=44363.48.3
        Validity
            Not Before: Oct 21 15:33:26 2025 GMT
            Not After : Oct 28 15:33:26 2025 GMT
        Subject: CN=cloudflareresearch.com
        Subject Public Key Info:
            Public Key Algorithm: id-ecPublicKey
                Public-Key: (256 bit)
                pub:
                    04:70:ed:e1:96:87:b4:22:ef:fb:dc:a9:cd:9c:5c:
                    ef:1e:9e:ab:1b:6d:d7:11:74:7b:76:c8:3c:a1:5f:
                    94:37:45:99:d8:80:e3:5c:24:4f:28:46:b5:bf:84:
                    60:d8:fc:eb:82:5a:c4:4e:33:90:c7:b3:36:51:0c:
                    92:6d:bf:88:27
                ASN1 OID: prime256v1
                NIST CURVE: P-256
        X509v3 extensions:
            X509v3 Key Usage: critical
                Digital Signature
            X509v3 Extended Key Usage:
                TLS Web Server Authentication
            X509v3 Subject Alternative Name:
                DNS:cloudflareresearch.com, DNS:static-ct.cloudflareresearch.com
    Signature Algorithm: 1.3.6.1.4.1.44363.47.0
    Signature Value:
        00:00:00:00:00:00:02:00:00:00:00:00:00:00:02:58:00:e0:
        44:be:03:a5:bd:6a:b7:f2:9e:39:77:4c:16:4c:f8:06:e5:e1:
        55:c0:93:21:c6:79:83:3c:dd:5b:e6:57:89:c0:75:b3:4c:ec:
        75:8a:0b:53:a0:ca:1c:07:0c:1a:92:dd:c7:7c:a2:23:5d:83:
        0e:e4:23:43:38:af:43:20:a8:66:44:34:95:87:ea:2b:f0:0f:
        16:52:bb:ea:67:67:1e:89:36:4f:90:d4:05:55:89:46:f1:b7:
        b6:68:84:d3:57:31:ae:2b:c3:79:31:86:85:9d:24:ed:cf:25:
        a4:5c:fd:8f:f6:76:14:55:dd:67:2e:df:d6:8c:25:0d:52:48:
        c8:e3:fe:f9:7c:e6:a5:30:52:a5:b5:c7:3a:89:a5:c1:f6:4b:
        5b:95:ef:70:b8:91:fc:61:0f:6d:16:de:39:e9:a0:59:49:2b:
        34:71:7c:2a:16:da:c7:af:de:f7:01:94:10:c4:62:d1:f5:00:
        87:bd:e8:a2:f4:df:3b:35:79:27:0e:fc:cc:43:e7:60:5a:df:
        df:06:e8:d3:7e:eb:b3:bf:7b:25:43:0f:34:9a:26:c0:d3:6d:
        5d:0c:28:bc:87:58:58:15:00:00
While some of the parameters probably look familiar, others will look unusual. On the familiar side, the subject and public key are exactly what we might expect: the DNS name is cloudflareresearch.com and the public key is for a familiar signature algorithm, ECDSA-P256. This algorithm is not PQ, of course — in the future we would put ML-DSA-44 there instead.
On the unusual side, OpenSSL appears to not recognize the signature algorithm of the issuer and just prints the raw OID and bytes of the signature. There’s a good reason for this: the MTC does not have a signature in it at all! So what exactly are we looking at?
The trick to leave out signatures is that a Merkle Tree Certification Authority (MTCA) produces its signatureless certificates in batches rather than individually. In place of a signature, the certificate has an inclusion proof of the certificate in a batch of certificates signed by the MTCA.
To understand how inclusion proofs work, let’s think about a slightly simplified version of the MTC specification. To issue a batch, the MTCA arranges the unsigned certificates into a data structure called a Merkle tree that looks like this:
Each leaf of the tree corresponds to a certificate, and each inner node is equal to the hash of its children. To sign the batch, the MTCA uses its secret key to sign the head of the tree. The structure of the tree guarantees that each certificate in the batch was signed by the MTCA: if we tried to tweak the bits of any one of the certificates, the treehead would end up having a different value, which would cause the signature to fail.
An inclusion proof for a certificate consists of the hash of each sibling node along the path from the certificate to the treehead:
Given a validated treehead, this sequence of hashes is sufficient to prove inclusion of the certificate in the tree. This means that, in order to validate an MTC, the client also needs to obtain the signed treehead from the MTCA.
This is the key to MTC’s efficiency:
Signed treeheads can be disseminated to clients out-of-band and validated offline. Each validated treehead can then be used to validate any certificate in the corresponding batch, eliminating the need to obtain a signature for each server certificate.
During the TLS handshake, the client tells the server which treeheads it has. If the server has a signatureless certificate covered by one of those treeheads, then it can use that certificate to authenticate itself. That’s 1 signature,1 public key and 1 inclusion proof per handshake, both for the server being authenticated.
Now, that’s the simplified version. MTC proper has some more bells and whistles. To start, it doesn’t create a separate Merkle tree for each batch, but it grows a single large tree, which is used for better transparency. As this tree grows, periodically (sub)tree heads are selected to be shipped to browsers, which we call landmarks. In the common case browsers will be able to fetch the most recent landmarks, and servers can wait for batch issuance, but we need a fallback: MTC also supports certificates that can be issued immediately and don’t require landmarks to be validated, but these are not as small. A server would provision both types of Merkle tree certificates, so that the common case is fast, and the exceptional case is slow, but at least it’ll work.
Experimental deployment
Ever since early designs for MTCs emerged, we’ve been eager to experiment with the idea. In line with the IETF principle of “running code”, it often takes implementing a protocol to work out kinks in the design. At the same time, we cannot risk the security of users. In this section, we describe our approach to experimenting with aspects of the Merkle Tree Certificates design without changing any trust relationships.
Let’s start with what we hope to learn. We have lots of questions whose answers can help to either validate the approach, or uncover pitfalls that require reshaping the protocol — in fact, an implementation of an early MTC draft by Maximilian Pohl and Mia Celeste did exactly this. We’d like to know:
What breaks? Protocol ossification (the tendency of implementation bugs to make it harder to change a protocol) is an ever-present issue with deploying protocol changes. For TLS in particular, despite having built-in flexibility, time after time we’ve found that if that flexibility is not regularly used, there will be buggy implementations and middleboxes that break when they see things they don’t recognize. TLS 1.3 deployment took years longer than we hoped for this very reason. And more recently, the rollout of PQ key exchange in TLS caused the Client Hello to be split over multiple TCP packets, something that many middleboxes weren’t ready for.
What is the performance impact? In fact, we expect MTCs to reduce the size of the handshake, even compared to today’s non-PQ certificates. They will also reduce CPU cost: ML-DSA signature verification is about as fast as ECDSA, and there will be far fewer signatures to verify. We therefore expect to see a reduction in latency. We would like to see if there is a measurable performance improvement.
What fraction of clients will stay up to date? Getting the performance benefit of MTCs requires the clients and servers to be roughly in sync with one another. We expect MTCs to have fairly short lifetimes, a week or so. This means that if the client’s latest landmark is older than a week, the server would have to fallback to a larger certificate. Knowing how often this fallback happens will help us tune the parameters of the protocol to make fallbacks less likely.
In order to answer these questions, we are implementing MTC support in our TLS stack and in our certificate issuance infrastructure. For their part, Chrome is implementing MTC support in their own TLS stack and will stand up infrastructure to disseminate landmarks to their users.
As we’ve done in past experiments, we plan to enable MTCs for a subset of our free customers with enough traffic that we will be able to get useful measurements. Chrome will control the experimental rollout: they can ramp up slowly, measuring as they go and rolling back if and when bugs are found.
Which leaves us with one last question: who will run the Merkle Tree CA?
Bootstrapping trust from the existing WebPKI
Standing up a proper CA is no small task: it takes years to be trusted by major browsers. That’s why Cloudflare isn’t going to become a “real” CA for this experiment, and Chrome isn’t going to trust us directly.
Instead, to make progress on a reasonable timeframe, without sacrificing due diligence, we plan to “mock” the role of the MTCA. We will run an MTCA (on Workers based on our StaticCT logs), but for each MTC we issue, we also publish an existing certificate from a trusted CA that agrees with it. We call this the bootstrap certificate. When Chrome’s infrastructure pulls updates from our MTCA log, they will also pull these bootstrap certificates, and check whether they agree. Only if they do, they’ll proceed to push the corresponding landmarks to Chrome clients. In other words, Cloudflare is effectively just “re-encoding” an existing certificate (with domain validation performed by a trusted CA) as an MTC, and Chrome is using certificate transparency to keep us honest.
Conclusion
With almost 50% of our traffic already protected by post-quantum encryption, we’re halfway to a fully post-quantum secure Internet. The second part of our journey, post-quantum certificates, is the hardest yet though. A simple drop-in upgrade has a noticeable performance impact and no security benefit before Q-day. This means it’s a hard sell to enable today by default. But here we are playing with fire: migrations always take longer than expected. If we want to keep an ubiquitously private and secure Internet, we need a post-quantum solution that’s performant enough to be enabled by default today.
Merkle Tree Certificates (MTCs) solves this problem by reducing the number of signatures and public keys to the bare minimum while maintaining the WebPKI’s essential properties. We plan to roll out MTCs to a fraction of free accounts by early next year. This does not affect any visitors that are not part of the Chrome experiment. For those that are, thanks to the bootstrap certificates, there is no impact on security.
We’re excited to keep the Internet fast and secure, and will report back soon on the results of this experiment: watch this space! MTC is evolving as we speak, if you want to get involved, please join the IETF PLANTS mailing list.
Two people found the solution. They used the power of research, not cryptanalysis, finding clues amongst the Sanborn papers at the Smithsonian’s Archives of American Art.
This comes as an awkward time, as Sanborn is auctioning off the solution. There were legal threats—I don’t understand their basis—and the solvers are not publishing their solution.
The web is the most powerful application platform in existence. As long as you have the right API, you can safely run anything you want in a browser.
Well… anything but cryptography.
It is as true today as it was in 2011 that Javascript cryptography is Considered Harmful. The main problem is code distribution. Consider an end-to-end-encrypted messaging web application. The application generates cryptographic keys in the client’s browser that lets users view and send end-to-end encrypted messages to each other. If the application is compromised, what would stop the malicious actor from simply modifying their Javascript to exfiltrate messages?
It is interesting to note that smartphone apps don’t have this issue. This is because app stores do a lot of heavy lifting to provide security for the app ecosystem. Specifically, they provide integrity, ensuring that apps being delivered are not tampered with, consistency, ensuring all users get the same app, and transparency, ensuring that the record of versions of an app is truthful and publicly visible.
It would be nice if we could get these properties for our end-to-end encrypted web application, and the web as a whole, without requiring a single central authority like an app store. Further, such a system would benefit all in-browser uses of cryptography, not just end-to-end-encrypted apps. For example, many web-based confidential LLMs, cryptocurrency wallets, and voting systems use in-browser Javascript cryptography for the last step of their verification chains.
In this post, we will provide an early look at such a system, called Web Application Integrity, Consistency, and Transparency (WAICT) that we have helped author. WAICT is a W3C-backed effort among browser vendors, cloud providers, and encrypted communication developers to bring stronger security guarantees to the entire web. We will discuss the problem we need to solve, and build up to a solution resembling the current transparency specification draft. We hope to build even wider consensus on the solution design in the near future.
Defining the Web Application
In order to talk about security guarantees of a web application, it is first necessary to define precisely what the application is. A smartphone application is essentially just a zip file. But a website is made up of interlinked assets, including HTML, Javascript, WASM, and CSS, that can each be locally or externally hosted. Further, if any asset changes, it could drastically change the functioning of the application. A coherent definition of an application thus requires the application to commit to precisely the assets it loads. This is done using integrity features, which we describe now.
Subresource Integrity
An important building block for defining a single coherent application is subresource integrity (SRI). SRI is a feature built into most browsers that permits a website to specify the cryptographic hash of external resources, e.g.,
This causes the browser to fetch underscore.js from cdnjs.cloudflare.com and verify that its SHA-512 hash matches the given hash in the tag. If they match, the script is loaded. If not, an error is thrown and nothing is executed.
If every external script, stylesheet, etc. on a page comes with an SRI integrity attribute, then the whole page is defined by just its HTML. This is close to what we want, but a web application can consist of many pages, and there is no way for a page to enforce the hash of the pages it links to.
Integrity Manifest
We would like to have a way of enforcing integrity on an entire site, i.e., every asset under a domain. For this, WAICT defines an integrity manifest, a configuration file that websites can provide to clients. One important item in the manifest is the asset hashes dictionary, mapping a hash belonging to an asset that the browser might load from that domain, to the path of that asset. Assets that may occur at any path, e.g., an error page, map to the empty string:
The other main component of the manifest is the integrity policy, which tells the browser which data types are being enforced and how strictly. For example, the policy in the manifest below will:
Reject any script before running it, if it’s missing an SRI tag and doesn’t appear in the hashes
Reject any WASM possibly after running it, if it’s missing an SRI tag and doesn’t appear in hashes
Thus, when both SRI and integrity manifests are used, the entire site and its interpretation by the browser is uniquely determined by the hash of the integrity manifest. This is exactly what we wanted. We have distilled the problem of endowing authenticity, consistent distribution, etc. to a web application to one of endowing the same properties to a single hash.
Achieving Transparency
Recall, a transparent web application is one whose code is stored in a publicly accessible, append-only log. This is helpful in two ways: 1) if a user is served malicious code and they learn about it, there is a public record of the code they ran, and so they can prove it to external parties, and 2) if a user is served malicious code and they don’t learn about it, there is still a chance that an external auditor may comb through the historical web application code and find the malicious code anyway. Of course, transparency does not help detect malicious code or even prevent its distribution, but it at least makes it publicly auditable.
Now that we have a single hash that commits to an entire website’s contents, we can talk about ensuring that that hash ends up in a public log. We have several important requirements here:
Do not break existing sites. This one is a given. Whatever system gets deployed, it should not interfere with the correct functioning of existing websites. Participation in transparency should be strictly opt-in.
No added round trips. Transparency should not cause extra network round trips between the client and the server. Otherwise there will be a network latency penalty for users who want transparency.
User privacy. A user should not have to identify themselves to any party more than they already do. That means no connections to new third parties, and no sending identifying information to the website.
User statelessness. A user should not have to store site-specific data. We do not want solutions that rely on storing or gossipping per-site cryptographic information.
Non-centralization. There should not be a single point of failure in the system—if any single party experiences downtime, the system should still be able to make progress. Similarly, there should be no single point of trust—if a user distrusts any single party, the user should still receive all the security benefits of the system.
Ease of opt-in. The barrier of entry for transparency should be as low as possible. A site operator should be able to start logging their site cheaply and without being an expert.
Ease of opt-out. It should be easy for a website to stop participating in transparency. Further, to avoid accidental lock-in like the defunct HPKP spec, it should be possible for this to happen even if all cryptographic material is lost, e.g., in the seizure or selling of a domain.
Opt-out is transparent. As described before, because transparency is optional, it is possible for an attacker to disable the site’s transparency, serve malicious content, then enable transparency again. We must make sure this kind of attack is detectable, i.e., the act of disabling transparency must itself be logged somewhere.
Monitorability. A website operator should be able to efficiently monitor the transparency information being published about their website. In particular, they should not have to run a high-network-load, always-on program just to notify them if their site has been hijacked.
With these requirements in place, we can move on to construction. We introduce a data structure that will be essential to the design.
Hash Chain
Almost everything in transparency is an append-only log, i.e., a data structure that acts like a list and has the ability to produce an inclusion proof, i.e., a proof that an element occurs at a particular index in the list; and a consistency proof, i.e., a proof that a list is an extension of a previous version of the list. A consistency proof between two lists demonstrates that no elements were modified or deleted, only added.
The simplest possible append-only log is a hash chain, a list-like data structure wherein each subsequent element is hashed into the running chain hash. The final chain hash is a succinct representation of the entire list.
A hash chain. The green nodes represent the chain hash, i.e., the hash of the element below it, concatenated with the previous chain hash.
The proof structures are quite simple. To prove inclusion of the element at index i, the prover provides the chain hash before i, and all the elements after i:
Proof of inclusion for the second element in the hash chain. The verifier knows only the final chain hash. It checks equality of the final computed chain hash with the known final chain hash. The light green nodes represent hashes that the verifier computes.
Similarly, to prove consistency between the chains of size i and j, the prover provides the elements between i and j:
Proof of consistency of the chain of size one and chain of size three. The verifier has the chain hashes from the starting and ending chains. It checks equality of the final computed chain hash with the known ending chain hash. The light green nodes represent hashes that the verifier computes.
Building Transparency
We can use hash chains to build a transparency scheme for websites.
Per-Site Logs
As a first step, let’s give every site its own log, instantiated as a hash chain (we will discuss how these all come together into one big log later). The items of the log are just the manifest of the site at a particular point in time:
A site’s hash chain-based log, containing three historical manifests.
In reality, the log does not store the manifest itself, but the manifest hash. Sites designate an asset host that knows how to map hashes to the data they reference. This is a content-addressable storage backend, and can be implemented using strongly cached static hosting solutions.
A log on its own is not very trustworthy. Whoever runs the log can add and remove elements at will and then recompute the hash chain. To maintain the append-only-ness of the chain, we designate a trusted third party, called a witness. Given a hash chain consistency proof and a new chain hash, a witness:
Verifies the consistency proof with respect to its old stored chain hash, and the new provided chain hash.
If successful, signs the new chain hash along with a signature timestamp.
Now, when a user navigates to a website with transparency enabled, the sequence of events is:
The site serves its manifest, an inclusion proof showing that the manifest appears in the log, and all the signatures from all the witnesses who have validated the log chain hash.
The browser verifies the signatures from whichever witnesses it trusts.
The browser verifies the inclusion proof. The manifest must be the newest entry in the chain (we discuss how to serve old manifests later).
The browser proceeds with the usual manifest and SRI integrity checks.
At this point, the user knows that the given manifest has been recorded in a log whose chain hash has been saved by a trustworthy witness, so they can be reasonably sure that the manifest won’t be removed from history. Further, assuming the asset host functions correctly, the user knows that a copy of all the received code is readily available.
The need to signal transparency. The above algorithm works, but we have a problem: if an attacker takes control of a site, they can simply stop serving transparency information and thus implicitly disable transparency without detection. So we need an explicit mechanism that keeps track of every website that has enrolled into transparency.
The Transparency Service
To store all the sites enrolled into transparency, we want a global data structure that maps a site domain to the site log’s chain hash. One efficient way of representing this is a prefix tree (a.k.a., a trie). Every leaf in the tree corresponds to a site’s domain, and its value is the chain hash of that site’s log, the current log size, and the site’s asset host URL. For a site to prove validity of its transparency data, it will have to present an inclusion proof for its leaf. Fortunately, these proofs are efficient for prefix trees.
A prefix tree with four elements. Each leaf’s path corresponds to a domain. Each leaf’s value is the chain hash of its site’s log.
To add itself to the tree, a site proves possession of its domain to the transparency service, i.e., the party that operates the prefix tree, and provides an asset host URL. To update the entry, the site sends the new entry to the transparency service, which will compute the new chain hash. And to unenroll from transparency, the site just requests to have its entry removed from the tree (an adversary can do this too; we discuss how to detect this below).
Proving to Witnesses and Browsers
Now witnesses only need to look at the prefix tree instead of individual site logs, and thus they must verify whole-tree updates. The most important thing to ensure is that every site’s log is append-only. So whenever the tree is updated, it must produce a “proof” containing every new/deleted/modified entry, as well as a consistency proof for each entry showing that the site log corresponding to that entry has been properly appended to. Once the witness has verified this prefix tree update proof, it signs the root.
The sequence of updating a site’s assets and serving the site with transparency enabled.
The client-side verification procedure is as in the previous section, with two modifications:
The client now verifies two inclusion proofs: one for the integrity policy’s membership in the site log, and one for the site log’s membership in a prefix tree.
The client verifies the signature over the prefix tree root, since the witness no longer signs individual chain hashes. As before, the acceptable public keys are whichever witnesses the client trusts.
Signaling transparency. Now that there is a single source of truth, namely the prefix tree, a client can know a site is enrolled in transparency by simply fetching the site’s entry in the tree. This alone would work, but it violates our requirement of “no added round trips,” so we instead require that client browsers will ship with the list of sites included in the prefix tree. We call this the transparency preload list.
If a site appears in the preload list, the browser will expect it to provide an inclusion proof in the prefix tree, or else a proof of non-inclusion in a newer version of the prefix tree, thereby showing they’ve unenrolled. The site must provide one of these proofs until the last preload list it appears in has expired. Finally, even though the preload list is derived from the prefix tree, there is nothing enforcing this relationship. Thus, the preload list should also be published transparently.
Filling in Missing Properties
Remember we still have the requirements of monitorability, opt-out being transparent, and no single point of failure/trust. We fill in those details now.
Adding monitorability. So far, in order for a site operator to ensure their site was not hijacked, they would have to constantly query every transparency service for its domain and verify that it hasn’t been tampered with. This is certainly better than the 500k events per hour that CT monitors have to ingest, but it still requires the monitor to be constantly polling the prefix tree, and it imposes a constant load for the transparency service.
We add a field to the prefix tree leaf structure: the leaf now stores a “created” timestamp, containing the time the leaf was created. Witnesses ensure that the “created” field remains the same over all leaf updates (and it is deleted when the leaf is deleted). To monitor, a site operator need only keep the last observed “created” and “log size” fields of its leaf. If it fetches the latest leaf and sees both unchanged, it knows that no changes occurred since the last check.
Adding transparency of opt-out. We must also do the same thing as above for leaf deletions. When a leaf is deleted, a monitor should be able to learn when the deletion occurred within some reasonable time frame. Thus, rather than outright removing a leaf, the transparency service responds to unenrollment requests by replacing the leaf with a tombstone value, containing just a “created” timestamp. As before, witnesses ensure that this field remains unchanged until the leaf is permanently deleted (after some visibility period) or re-enrolled.
Permitting multiple transparency services. Since we require that there be no single point of failure or trust, we imagine an ecosystem where there are a handful of non-colluding, reasonably trustworthy transparency service providers, each with their own prefix tree. Like Certificate Transparency (CT), this set should not be too large. It must be small enough that reasonable levels of trust can be established, and so that independent auditors can reasonably handle the load of verifying all of them.
Ok that’s the end of the most technical part of this post. We’re now going to talk about how to tweak this system to provide all kinds of additional nice properties.
(Not) Achieving Consistency
Transparency would be useless if, every time a site updates, it serves 100,000 new versions of itself. Any auditor would have to go through every single version of the code in order to ensure no user was targeted with malware. This is bad even if the velocity of versions is lower. If a site publishes just one new version per week, but every version from the past ten years is still servable, then users can still be served extremely old, potentially vulnerable versions of the site, without anyone knowing. Thus, in order to make transparency valuable, we need consistency, the property that every browser sees the same version of the site at a given time.
We will not achieve the strongest version of consistency, but it turns out that weaker notions are sufficient for us. If, unlike the above scenario, a site had 8 valid versions of itself at a given time, then that would be pretty manageable for an auditor. So even though it’s true that users don’t all see the same version of the site, they will all still benefit from transparency, as desired.
We describe two types of inconsistency and how we mitigate them.
Tree Inconsistency
Tree inconsistency occurs when transparency services’ prefix trees disagree on the chain hash of a site, thus disagreeing on the history of the site. One way to fully eliminate this is to establish a consensus mechanism for prefix trees. A simple one is majority voting: if there are five transparency services, a site must present three tree inclusion proofs to a user, showing the chain hash is present in three trees. This, of course, triples the tree inclusion proof size, and lowers the fault tolerance of the entire system (if three log operators go down, then no transparent site can publish any updates).
Instead of consensus, we opt to simply limit the amount of inconsistency by limiting the number of transparency services. In 2025, Chrome trusts eight Certificate Transparency logs. A similar number of transparency services would be fine for our system. Plus, it is still possible to detect and prove the existence of inconsistencies between trees, since roots are signed by witnesses. So if it becomes the norm to use the same version on all trees, then social pressure can be applied when sites violate this.
Temporal Inconsistency
Temporal inconsistency occurs when a user gets a newer or older version of the site (both still unexpired), depending on some external factors such as geographic location or cookie values. In the extreme, as stated above, if a signed prefix root is valid for ten years, then a site can serve a user any version of the site from the last ten years.
As with tree inconsistency, this can be resolved using consensus mechanisms. If, for example, the latest manifest were published on a blockchain, then a user could fetch the latest blockchain head and ensure they got the latest version of the site. However, this incurs an extra network round trip for the client, and requires sites to wait for their hash to get published on-chain before they can update. More importantly, building this kind of consensus mechanism into our specification would drastically increase its complexity. We’re aiming for v1.0 here.
We mitigate temporal inconsistency by requiring reasonably short validity periods for witness signatures. Making prefix root signatures valid for, e.g., one week would drastically limit the number of simultaneously servable versions. The cost is that site operators must now query the transparency service at least once a week for the new signed root and inclusion proof, even if nothing in the site changed. The sites cannot skip this, and the transparency service must be able to handle this load. This parameter must be tuned carefully.
Beyond Integrity, Consistency, and Transparency
Providing integrity, consistency, and transparency is already a huge endeavor, but there are some additional app store-like security features that can be integrated into this system without too much work.
Code Signing
One problem that WAICT doesn’t solve is that of provenance: where did the code the user is running come from, precisely? In settings where audits of code happen frequently, this is not so important, because some third party will be reading the code regardless. But for smaller self-hosted deployments of open-source software, this may not be viable. For example, if Alice hosts her own version of Cryptpad for her friend Bob, how can Bob be sure the code matches the real code in Cryptpad’s Github repo?
WEBCAT. The folks at the Freedom of Press Foundation (FPF) have built a solution to this, called WEBCAT. This protocol allows site owners to announce the identities of the developers that have signed the site’s integrity manifest, i.e., have signed all the code and other assets that the site is serving to the user. Users with the WEBCAT plugin can then see the developer’s Sigstore signatures, and trust the code based on that.
We’ve made WAICT extensible enough to fit WEBCAT inside and benefit from the transparency components. Concretely, we permit manifests to hold additional metadata, which we call extensions. In this case, the extension holds a list of developers’ Sigstore identities. To be useful, browsers must expose an API for browser plugins to access these extension values. With this API, independent parties can build plugins for whatever feature they wish to layer on top of WAICT.
Cooldown
So far we have not built anything that can prevent attacks in the moment. An attacker who breaks into a website can still delete any code-signing extensions, or just unenroll the site from transparency entirely, and continue with their attack as normal. The unenrollment will be logged, but the malicious code will not be, and by the time anyone sees the unenrollment, it may be too late.
To prevent spontaneous unenrollment, we can enforce unenrollment cooldown client-side. Suppose the cooldown period is 24 hours. Then the rule is: if a site appears on the preload list, then the client will require that either 1) the site have transparency enabled, or 2) the site have a tombstone entry that is at least 24 hours old. Thus, an attacker will be forced to either serve a transparency-enabled version of the site, or serve a broken site for 24 hours.
Similarly, to prevent spontaneous extension modifications, we can enforce extension cooldown on the client. We will take code signing as an example, saying that any change in developer identities requires a 24 hour waiting period to be accepted. First, we require that extension dev-ids has a preload list of its own, letting the client know which sites have opted into code signing (if a preload list doesn’t exist then any site can delete the extension at any time). The client rule is as follows: if the site appears in the preload list, then both 1) dev-ids must exist as an extension in the manifest, and 2) dev-ids-inclusion must contain an inclusion proof showing that the current value of dev-ids was in a prefix tree that is at least 24 hours old. With this rule, a client will reject values of dev-ids that are newer than a day. If a site wants to delete dev-ids, they must 1) request that it be removed from the preload list, and 2) in the meantime, replace the dev-ids value with the empty string and update dev-ids-inclusion to reflect the new value.
Deployment Considerations
There are a lot of distinct roles in this ecosystem. Let’s sketch out the trust and resource requirements for each role.
Transparency service. These parties store metadata for every transparency-enabled site on the web. If there are 100 million domains, and each entry is 256B each (a few hashes, plus a URL), this comes out to 26GB for a single tree, not including the intermediate hashes. To prevent size blowup, there would probably have to be a pruning rule that unenrolls sites after a long inactivity period. Transparency services should have largely uncorrelated downtime, since, if all services go down, no transparency-enabled site can make any updates. Thus, transparency services must have a moderate amount of storage, be relatively highly available, and have downtime periods uncorrelated with each other.
Transparency services require some trust, but their behavior is narrowly constrained by witnesses. Theoretically, a service can replace any leaf’s chain hash with its own, and the witness will validate it (as long as the consistency proof is valid). But such changes are detectable by anyone that monitors that leaf.
Witness. These parties verify prefix tree updates and sign the resulting roots. Their storage costs are similar to that of a transparency service, since they must keep a full copy of a prefix tree for every transparency service they witness. Also like the transparency services, they must have high uptime. Witnesses must also be trusted to keep their signing key secret for a long period of time, at least long enough to permit browser trust stores to be updated when a new key is created.
Asset host. These parties carry little trust. They cannot serve bad data, since any query response is hashed and compared to a known hash. The only malicious behavior an asset host can do is refuse to respond to queries. Asset hosts can also do this by accident due to downtime.
Client. This is the most trust-sensitive part. The client is the software that performs all the transparency and integrity checks. This is, of course, the web browser itself. We must trust this.
We at Cloudflare would like to contribute what we can to this ecosystem. It should be possible to run both a transparency service and a witness. Of course, our witness should not monitor our own transparency service. Rather, we can witness other organizations’ transparency services, and our transparency service can be witnessed by other organizations.
Supporting Alternate Ecosystems
WAICT should be compatible with non-standard ecosystems, ones where the large players do not really exist, or at least not in the way they usually do. We are working with the FPF on defining transparency for alternate ecosystems with different network and trust environments. The primary example we have is that of the Tor ecosystem.
A paranoid Tor user may not trust existing transparency services or witnesses, and there might not be any other trusted party with the resources to self-host these functionalities. For this use case, it may be reasonable to put the prefix tree on a blockchain somewhere. This makes the usual domain validation impossible (there’s no validator server to speak of), but this is fine for onion services. Since an onion address is just a public key, a signature is sufficient to prove ownership of the domain.
One consequence of a consensus-backed prefix tree is that witnesses are now unnecessary, and there is only need for the single, canonical, transparency service. This mostly solves the problems of tree inconsistency at the expense of latency of updates.
Next Steps
We are still very early in the standardization process. One of the more immediate next steps is to get subresource integrity working for more data types, particularly WASM and images. After that, we can begin standardizing the integrity manifest format. And then after that we can start standardizing all the other features. We intend to work on this specification hand-in-hand with browsers and the IETF, and we hope to have some exciting betas soon.
In the meantime, you can follow along with our transparency specification draft, check out the open problems, and share your ideas. Pull requests and issues are always welcome!
Acknowledgements
Many thanks to Dennis Jackson from Mozilla for the lengthy back-and-forth meetings on design, to Giulio B and Cory Myers from FPF for their immensely helpful influence and feedback, and to Richard Hansen for great feedback.
Cloudflare is well ahead of NIST’s schedule. Today, over 45% of human-generated Internet traffic sent to Cloudflare’s network is already post-quantum encrypted. Because we believe that a secure and private Internet should be free and accessible to all, we’re on a mission to include PQC in all our products, without specialized hardware, and at no extra cost to our customers and end users.
That’s why we’re proud to announce that Cloudflare’s WARP client now supports post-quantum key agreement — both in our free consumer WARP client 1.1.1.1, and in our enterprise WARP client, the Cloudflare One Agent.
Post-quantum tunnels using the WARP client
This upgrade of the WARP client to post-quantum key agreement provides end users with immediate protection for their Internet traffic against harvest-now-decrypt-later attacks. The value proposition is clear — by tunneling your Internet traffic over the WARP client’s post-quantum MASQUE tunnels, you get immediate post-quantum encryption of your network traffic. And this holds even if the individual connections sent through the tunnel have not yet been upgraded to post-quantum cryptography.
We have upgraded the Cloudflare One Agentto post-quantum key agreement, providing end-to-end post quantum protection for traffic sent to internal corporate resources.
When an end user installs the consumer WARP Client (1.1.1.1), the WARP client wraps the end user’s network traffic in a post-quantum encrypted MASQUE tunnel. As shown in the figure below, the MASQUE tunnel protects the traffic on its way to Cloudflare’s global network (link (1)). Cloudflare’s global network then uses post-quantum encrypted tunnels to bring the traffic as close as possible to its final destination (link (2)). Finally, the traffic is forwarded over the public Internet to the origin server (i.e. its final destination). That final connection (link (3)) may or may not be post-quantum (PQ). It will not be PQ if the origin server is not PQ. It will be PQ if the origin server is (a) upgraded to PQC, and (b) the end user is connecting to over a client that supports PQC (like Chrome, Edge or Firefox). In the future, Automatic SSL/TLS will ensure that your entire connection will be PQ as long as the origin server is behind Cloudflare and supports PQ connections (even if your browser doesn’t).
Consumer WARP client (1.1.1.1) is now upgraded to post-quantum key agreement.
The cryptography landscape
Before we get into the details of our upgrade to the WARP client, let’s review the different cryptographic primitives involved in the transition to PQC.
Key agreement is a method by which two or more parties can establish a shared secret key over an insecure communication channel. This shared secret can then be used to encrypt and authenticate subsequent communications. Classical key agreement in Transport Layer Security (TLS) typically uses the Elliptic Curve Diffie Hellman (ECDH) cryptographic algorithm, whose security can be broken by a quantum computer using Shor’s algorithm.
This is why we upgraded the WARP client to post-quantum key agreement.
Post-quantum key agreement is already quite mature and performant; our experiments have shown that deploying the post-quantumModule-Lattice-Based Key-Encapsulation Mechanism (ML-KEM) algorithm in hybrid mode (in parallel with classical ECDH) over TLS 1.3 is actually more performant than using TLS 1.2 with classical cryptography.
Over one-third of the human-generated traffic to our network uses TLS 1.3 with hybrid post-quantum key agreement (shown as X25519MLKEM768 in the screen capture above); in fact, if you’re on a Chrome, Edge or Firefox browser, you’re probably reading this blog right now over a PQ encrypted connection.
Post-quantum digital signatures and certificates, by contrast, are still in the process of being standardized for use in TLS and the Internet’s Public Key Infrastructure (PKI). PQ signatures and certificates are required to prevent an active attacker who uses a quantum computer to forge a digital certificate/signature and then uses it to decrypt or manipulate communications by impersonating a trusted server. As far as we know, we don’t have such attackers yet, which is why post-quantum signatures and certificates are not widely deployed across the Internet. We have not yet upgraded the WARP client to PQ signatures and certificates, but we plan to do so soon.
A unique challenge: PQC upgrade in the WARP client
While Cloudflare is on the forefront of the PQC transition, a different kind of challenge emerged when we upgraded our WARP client. Unlike a server that we fully control and can hotfix at any time, our WARP client runs directly on end user devices. In fact, it runs on millions of end user devices that we do not control. This fundamental difference means that every time we update the WARP client, our release must work properly on the first try, with no room for error.
To make things even more challenging, we need to support the WARP client across five different operating systems (Windows, macOS, Linux, iOS, and Android/ChromeOS), while also ensuring consistency and reliability for both our consumer 1.1.1.1 WARP client and our Cloudflare One Agent. In addition, because the WARP client relies on the fairly new MASQUE protocol, which the industry only standardized in August 2022, we need to be extra careful to make sure our upgrade to post-quantum key agreement does not expose latent bugs or instabilities in the MASQUE protocol itself.
All these challenges point to a slow and careful transition to PQC in the WARP client, while still supporting customers that want to immediately activate PQC. To accomplish this, we used three techniques:
temporary PQC downgrades,
gradual rollout across our WARP client population, and
As we roll out PQ key agreement in MASQUE to the WARP client, we want to make sure we don’t have WARP clients that struggle to connect due to an error, middlebox, or a latent implementation bug triggered by our PQC migration. One way to accomplish this level of robustness is to have clients downgrade to a classic cryptographic connection if they fail to negotiate a PQ connection.
To really understand this strategy, we need to review the concept of cryptographic downgrades. In cryptography, a downgrade attack is a cyber attack where an attacker forces a system to abandon a secure cryptographic algorithm in favor of an older, less secure, or even unencrypted one that allows the attacker to introspect on the communications. Thus, when newly rolling out a PQ encryption, it is standard practice to ensure that: if the client and server both support PQ encryption, it should not be possible for an attacker to downgrade their connection to a classic encryption.
Thus, to prevent downgrade attacks, we should ensure that if the client and server both support PQC, but fail to negotiate a PQC connection, then the connection will just fail. However, while this prevents downgrade attacks, it also creates problems with robustness.
We cannot have both robustness (i.e. the ability for client to downgrade to a classical connection if the PQC fails) and security against downgrades (i.e. the client is forbidden to downgrade to classical cryptography once it supports PQC) at the same time. We have to choose one. For this reason, we opted for a phased approach.
Phase 1: Automated PQC downgrades. We start by choosing robustness at the cost of providing security against downgrade attacks. In this phase, we support automated PQC downgrades — if a client fails to negotiate a PQC connection, it will downgrade to classical cryptography. That way, if there are bugs or other instability introduced by PQC, the client automatically downgrades to classical cryptography and the end user will not experience any issues. (Note: because MASQUE establishes a single very long-lived TLS connection only when the user logs in, an end user is unlikely to notice a downgrade.)
Phase 2: PQC with security against downgrades. Then, once the rollout is stable and we are convinced that there are no issues interfering with PQC, we will choose security against downgrade attacks over robustness. In this phase, if a client fails to negotiate a PQC connection, the connection will just fail, which provides security against downgrade attacks.
To implement this phased approach, we introduced an API flag that the client uses to determine how it should initiate TLS handshakes, which has three states:
No PQC: The client initiates a TLS handshake using classical cryptography only. .
PQC downgrades allowed: The client initiates a TLS handshake using post-quantum key agreement. If the PQC handshake negotiation fails, the client downgrades to classical cryptography. This flag supports Phase 1 of our rollout.
PQC only: The client initiates a TLS handshake using post-quantum key agreement cryptography. If the PQC handshake negotiation fails, the connection fails. This flag supports Phase 2 of our rollout.
With this as our framework, the next question becomes: what timing makes sense for this phased approach?
Gradual rollout across the WARP client population
To limit the risk of errors or latent implementation bugs triggered by our PQC migration, we gradually rolled out PQC across our population of WARP clients.
In Phase 1 of our rollout, we prioritized robustness rather than security against downgrade attacks. Thus, initially the API flag is set to “No PQC” for our entire client population, and we gradually turn on the “PQC downgrades allowed” across groups of clients. As we do this, we monitor whether any clients downgrade from PQC to classical cryptography. At the time of this writing, we have completed the Phase 1 rollout to all of our consumer WARP (1.1.1.1) clients. We expect to complete Phase 1 for our Cloudflare One Agent by the end of 2025.
Downgrades are not expected during Phase 1. In fact, downgrades indicate that there may be a latent issue that we have to fix. If you are using a WARP client and encounter issues that you believe might be related to PQC, you can let us know by using the feedback button in the WARP client interface (by clicking the bug icon in the top-right corner of the WARP client application). Enterprise users can also file a support ticket for the Cloudflare One Agent.
We plan to enter Phase 2 — where the API flag is set to “PQC only” in order to provide security against downgrade attacks — by summer of mid 2026.
MDM override
Finally, we know that some of our customers may not be willing to wait for us to complete this careful upgrade to PQC. So, those customers can activate PQC right now.
We’ve built a Mobile Device Management (MDM) override for the Cloudflare One Agent. MDM allows organizations to centrally manage, monitor, and secure mobile devices that access corporate resources; it works on multiple types of devices, not just mobile devices. The override for the Cloudflare One Agent allows an administrator (with permissions to manage the device) to turn on PQC. To use the MDM post-quantum override, set the ‘enable_post_quantum’ MDM flag to true. This flag takes precedence over the signal from the API flag we described earlier, and will activate PQC without downgrades. With this setting, the client will only negotiate a PQC connection. And if the PQC negotiation fails, the connection will fail, which provides security against downgrade attacks.
Ciphersuites, FIPS and Fedramp
The Federal Risk and Authorization Management Program (FedRAMP) is a U.S. government standard for securing federal data in the cloud. Cloudflare has a FedRAMP certification that requires that we use cryptographic ciphersuites that comply with FIPS (Federal Information Processing Standards) for certain products that are inside our FIPS boundary.
Because the WARP client is inside Cloudflare’s FIPS boundary for our FedRAMP certification, we had to ensure it uses FIPS-compliant cryptography. For internal links (where Cloudflare controls both sides of the connection) within the FIPS boundary, we currently use a hybrid key agreement consisting of FIPS-compliant EDCH using the P256 Elliptic curve, in parallel with an early version of ML-KEM-768 (which we started using before the ML-KEM standards were finalized) — a key agreement called P256Kyber768Draft00. To observe this ciphersuite in action in your WARP client, you can use the warp-cli tunnel stats utility. Here’s an example of what we find when PQC is enabled:
And here is an example when PQC is not enabled:
PQC tunnels for everyone
We believe that PQC should be available to everyone, without specialized hardware, at no additional cost. To that end, we’re proud to help shoulder the burden of the Internet’s upgrade to PQC.
A powerful strategy is to use tunnels protected by post-quantum key agreement to protect Internet traffic, in bulk, from harvest-now-decrypt-later attacks – even if the individual connections sent through the tunnel have not yet been upgraded to PQC. Eventually, we will upgrade these tunnels to also support post-quantum signatures and certificates, to stop active attacks by adversaries armed with quantum computers after Q-Day.
This staged approach keeps up with Internet standards. And the use of tunnels provides customers and end users with built-in cryptographic agility, so they can easily adapt to changes in the cryptographic landscape without a major architectural overhaul.
Cloudflare’s WARP client is just the latest tunneling technology that we’ve upgraded to post-quantum key agreement. You can try it out today for free on personal devices using our free consumer WARP client 1.1.1.1, or for your corporate devices using our free zero-trust offering for teams of under 50 users or a paid enterprise zero-trust or SASE subscription. Just download and install the client on your Windows, Linux, macOS, iOS, Android/ChromeOS device, and start protecting your network traffic with PQC.
Organizations have finite resources available to combat threats, both by the adversaries of today and those in the not-so-distant future that are armed with quantum computers. In this post, we provide guidance on what to prioritize to best prepare for the future, when quantum computers become powerful enough to break the conventional cryptography that underpins the security of modern computing systems. We describe how post-quantum cryptography (PQC) can be deployed on your existing hardware to protect from threats posed by quantum computing, and explain why quantum key distribution (QKD) and quantum random number generation (QRNG) are neither necessary nor sufficient for security in the quantum age.
Are you quantum ready?
“Quantum” is becoming one of the most heavily used buzzwords in the tech industry. What does it actually mean, and why should you care?
At its core, “quantum” refers to technologies that harness principles of quantum mechanics to perform tasks that are not feasible with classical computers. Quantum computers have exciting potential to unlock advancements in materials science and medicine, but also pose a threat to computer security systems. The term Q-day refers to the day that adversaries possess quantum computers that are large and stable enough to break the conventional public-key cryptography that secures much of today’s data and communications. Recent advances in quantum computing have made it clear that it is no longer a question of if Q-day will arrive, but when.
What does it mean, then, for your organization to be quantum ready? At Cloudflare, our definition is simple: your systems and communications should be secure even after Q-day.
However, this definition often gets muddied by vendors insisting that products built using quantum technology are required in order to secure an organization against quantum adversaries. In this blog post we explain why quantum technologies are neither necessary nor sufficient to protect against attacks by a quantum adversary.
The good news is that there is already a solution: post-quantum cryptography (PQC). PQC protects against attacks by quantum adversaries, but PQC is not a quantum technology — it runs on conventional computers without specialized hardware. You can use PQC today on the computers you already have, without buying expensive new hardware.
Post-quantum cryptography
We’ve written quite a few blog posts on post-quantum cryptography already, so we will keep this section brief.
The public-key cryptography that we’ve used for decades to secure our data and communications is based on math problems (like factoring large numbers) that are believed to be computationally hard to solve on conventional computers. If you can efficiently solve the underlying math problem, you can efficiently break the cryptography and the systems that depend on it. As it turns out, the math problems underlying much of today’s public-key cryptography can be efficiently solved by specialized algorithms, like Shor’s algorithm, on large-scale quantum computers.
Post-quantum cryptography (PQC) runs on your existing phones, laptops, and servers. PQC runs at Internet scale and can even be more performant than classical cryptography. Except in rare cases, like when you need additional hardware acceleration in cheap smartcards or to replace legacy systems that lack cryptographic agility, there is no need to purchase new hardware to migrate to PQC.
If you want to know how to protect your organization from security threats posed by quantum computers, you can stop reading now. Post-quantum cryptography is the solution.
Alternatively, you can read below for our perspective on hardware-based quantum security technologies that are sometimes marketed as security solutions.
This is exciting technology and fundamental scientific research. But this technology is not required to secure data and communications against quantum attackers.
In this section, we’ll explain why quantum security technologies do not need to be part of your quantum readiness strategy, and any decision to invest in quantum technology should not be based on a desire to defend data and communications systems against the threat of quantum adversaries. Instead, investments should be based on a desire to improve quantum technologies in their own right, for example to help with applications like chemistry, machine learning, and financial modeling.
Quantum key distribution (QKD) is a hardware-based solution to secure communications across point-to-point links. Rather than relying on hard mathematical problems, QKD relies on principles of quantum physics to establish a shared symmetric secret between two parties, while ensuring that eavesdropping can be detected. QKD provides security guarantees that are based on physical properties of the communication channel. Once a shared secret is established, parties can switch to traditional symmetric-key cryptography for secure communication. QKD is the first step towards a futuristic “quantum Internet.” However, there are some fundamental reasons why QKD cannot be a general replacement for classical cryptography running on conventional hardware.
Most importantly, QKD does not operate at Internet scale. QKD is used to establish an unauthenticated secret between pairs of parties with a direct physical link between them. The parties can then use an authentication mechanism based on conventional cryptography to bootstrap a secure communication channel over that link. While building dedicated physical links may be feasible for cross-datacenter communication or across major Internet backbones, it is not possible for most pairs of parties on the Internet. In particular, deploying QKD for the “last-mile” connection to end-user devices would require that each device has a direct physical connection to every server or device it needs to securely communicate with.
Connectivity aside, there’s a good reason why the Internet doesn’t rely on secure point-to-point links: they do not scale (or rather, they scale exponentially). Bringing a new device online would require a change to every other device it needs to communicate with, a massive operational burden on everyone. Fortunately, there’s a better way. The OSI model for networking provides an abstraction such that two parties can communicate even if they don’t share a direct physical link, so long as some chain of physical links exists between them. Public-key cryptography, invented in the seminal “New Directions in Cryptography” paper in 1976, allows two parties participating in the same public-key infrastructure to establish a secure end-to-end encrypted communication channel, without requiring any prior setup between them. The massive scaling enabled by these technologies is why the secure Internet exists as we know it. Secure point-to-point links are not part of the solution.
Lack of scalability is enough for us to disqualify QKD outright: if a technology can’t bring security to the whole Internet, we’re not going to spend much time on it.
The challenges with QKD don’t stop there though.
QKD touts theoretical security guarantees, but achieving security in practice is not so simple. QKD systems have been plagued by implementation attacks, both classical sidechannel attacks and new ones specific to the technology. Further, QKD works best over a special medium: either fiber or a vacuum. QKD has been demonstrated over the air, but performance and the implementation security mentioned before suffers. We still have not seen QKD work on a mobile phone or over Wi-Fi networks.
Further, neither QKD nor any other quantum technologies provide authentication to prove that the party on the other end of the key exchange is who you think they are. This opens the door for a classic monster in the middle (MITM) attack, where an adversary intercepts your connection, establishes a separate secure QKD link to you and your intended destination, and then sits in the middle reading and relaying all traffic. To prevent this, you must authenticate the identity of the party you are connecting to, using either pre-shared keys or conventional public-key cryptography. The bottom line is, whether or not you invest in QKD, you still need a solution for authentication to protect against active attackers armed with quantum computers. Practically speaking, that means you need PQC, but PQC is already a standalone solution that provides both authentication and key agreement, which leads to questions of why use QKD in the first place.
Some proponentsargue that QKD should be integrated into existing systems as an extra security layer. The value proposition of QKD relates to the “harvest now, decrypt later” threat. In public-key cryptography, the key exchange messages used to set up encryption keys to secure a communication channel are exchanged in full view of a potential adversary. If an adversary records the key exchange messages, they might hope to use improved techniques in the future to solve the hard math problems upon which the security of the key exchange relies, allowing them to recover the encryption keys and decrypt the communication. If encryption keys are exchanged directly via QKD instead, the eavesdropper protections provided by QKD stop an adversary from recording messages that could later allow them to recover the encryption key (e.g. by using a quantum computer or other advances in cryptanalysis). The problem is, however, that this “extra security layer” is brittle, and limited to a single physical link. As soon as the data is transmitted elsewhere — for instance at an Internet exchange point or to travel to an end-user — the QKD security ends. For the rest of its journey, the data is protected by standard protocols like TLS, making the value of the initial QKD link questionable.
While we hope the technology progresses, QKD is neither necessary nor sufficient for security against a quantum adversary. PQC is sufficient for security against a quantum adversary, already runs on your existing hardware, and works everywhere.
In cryptography and computer security, the essential property required from a random number generator is that the outputs are unpredictable and unbiased. This can be achieved by taking a small seed (say, 256 bits) of true randomness and feeding it to a cryptographically-secure pseudorandom number generator (CSPRNG) to produce an essentially limitless stream of pseudorandom output indistinguishable from true randomness. The randomness used to seed the CSPRNG can be based on either classical or quantum physical processes, as long as it is not known to the adversary. Whether or not you use a QRNG to generate the seed, a CSPRNG is essential for cryptographic applications.
We are the first to get excited about funnewsources of randomness. However, we’d like to emphasize that randomness derived from quantum effects is not necessary to combat threats from quantum computers. Quantum computers do not enable any practical new attacks against classical TRNGs in widespread use today. Your decision to invest in QRNGs should be based on a perceived improvement in the quality of randomness they produce and not on a perceived threat to classical TRNGs from quantum computing.
Post-quantum cryptography at Cloudflare
Cloudflare has been at the forefront of developing and deploying PQC, and we are committed to making PQC available for free and by default for all of our products. And we run it at scale — already over 40% of the human-generated traffic to our network uses PQC.
So what’s in that 40%? PQC is supported for all website and API traffic served through Cloudflare, most of Cloudflare’s internal network traffic, and traffic running over our Zero-Trust platform. All these connections use post-quantum key agreement to protect against the “harvest now, decrypt later” threat, where an adversary intercepts and stores encrypted data today with the hope of decrypting with a quantum computer or other cryptanalytic advances in the future. Key agreement is an important first step, but there’s still more work to be done. We’re actively working with stakeholders in the industry to prepare for the upcoming migration to post-quantum signatures to prevent active impersonation attacks from quantum adversaries (after Q-day).
Quantum readiness strategy
If purchasing quantum hardware is not necessary, how should organizations prepare for a quantum future? The most effective strategy will depend on your organization’s individual needs, but some general strategies will pay off for most organizations:
Investing in basic security practices is a good start. Hire the right expertise if you don’t already have it. Find vendors that support post-quantum encryption in their offerings today, and whose products are cryptographically agile so you can enjoy a seamless transition to post-quantum signatures and certificates when the industry migrates before Q-day. Follow a tunneling strategy: routing application traffic over the Internet via secure quantum safe tunnels allows you to reduce your attack surface area with minimal changes to existing systems. If you’re already a Cloudflare customer (or want to be), our Content Distribution Network and Zero Trust platform makes this easy. Learn more about how we can help at our Post-Quantum Cryptography webpage.
In our previous blog post (Part 1 of our key replication series), Automatically replicate your card payment keys across AWS Regions, we explored an event-driven, serverless architecture using AWS PrivateLink to securely replicate card payment keys across AWS Regions. That solution demonstrated how to build a custom replication framework for payment cryptography keys.
Based on customer feedback requesting a more automated, no-code approach, we’re excited to announce an additional option to this capability with Multi-Region keys for AWS Payment Cryptography in Part 2 of our series.
By using this new feature, you can automatically synchronize payment cryptography keys from a primary Region to other Regions that you select, improving resilience and availability of payment applications. You can also choose between account-level replication or key-level replication, giving more flexibility in how to manage payment keys across Regions.
Multi-Region keys: Overview and benefits
The new Multi-Region key replication feature for AWS Payment Cryptography offers you flexible control over your key replication strategy through the following primary capabilities:
Control whether keys are replicated
Select specific Regions for key replication
Manage replication configuration changes
Configure either account-level or key-level replication to meet business needs
Multi-Region keys help deliver several benefits for global payment operations, including:
Improved availability: Access your payment keys even if a Region becomes unavailable
Disaster recovery: Maintain business continuity with replicated keys across Regions
Global operations: Support payment processing across multiple geographic regions
Simplified management: Centralized control with distributed availability
Consistent key IDs: The same key ID across Regions simplifies application development
Configuration options
Payment Cryptography provides two distinct methods for configuring Multi-Region key replication, giving flexibility to implement a strategy that best fits your organization’s needs. You can choose between a broad, account-level approach or a more granular, key-level method.
Account-level
With account-level configuration, AWS automatically replicates exportable symmetric keys created in your Payment Cryptography account from your designated primary Region to other Regions you specify. This simplifies key management in multi-Region deployments, provides consistent key availability in the Regions that you specify, and reduces the operational overhead of key management.
To configure account-level replication using the AWS Command Line Interface (AWS CLI), use the new enable-default-key-replication-regions API to set the Regions where AWS will replicate your keys. To remove Regions from your default replication list, use the disable-default-key-replication-regions API.
Note: Only symmetric keys created after the account-level replication is enabled will be replicated.
Key-level replication
By using key-level replication, you can achieve more granular control by:
Designating specific keys as multi-Region keys
Defining custom replication targets for each multi-Region key
Maintaining Region-specific keys when needed
Note: Within each Region, Payment Cryptography maintains redundancy of your keys across multiple Availability Zones for high availability. Multi-Region key replication extends across geographic boundaries, giving you additional resilience against Regional outages while maintaining control over where your keys are stored.
You can specify replication Regions during key creation using the --replication-regions parameter, using the AWS CLI, with the create-key or import-key APIs. For existing keys, you can use the new add-key-replication-regions and remove-key-replication-regions APIs to manage which regions receive your replicated keys.
Important: When you specify replication Regions during key creation, these settings take precedence over default replication Regions configured at the account level.
How it works
Figure 1 shows the process when you replicate a key in Payment Cryptography.
The key is created in your designated primary Region
Payment Cryptography automatically replicates the key material asynchronously to the specified replica Regions
The replicated keys maintain the same key ID across Regions; only the Region portion of the Amazon Resource Name (ARN) changes
The key in the primary Region is marked with MultiRegionKeyType: PRIMARY
Keys in replica Regions are marked with MultiRegionKeyType: REPLICA and include a reference to the primary Region
When deleting a key, its deletion cascades from the primary to replica Regions
Figure 1: Representation of key replication from us-east-1 to us-west-2
Example: Creating a multi-Region key at key level
The following is an example of creating a card verification key (CVK) in the primary Region (us-east-1) with replication to us-west-2:
When using multi-Region keys, several important aspects should be considered. Multi-Region key replication supports only symmetric keys with the exportable attribute enabled, and asymmetric keys are not supported. For billing purposes, AWS bills per key per Region, which means replicating to three Regions incurs costs for the primary key plus costs for each key in the replica Regions.
Key aliases and tags require separate management in each Region because they are not part of the replication process. While primary keys support modifications and updates, replica keys are read-only copies that support only cryptographic operations. Modifications must be made to the key in the primary Region, and Payment Cryptography automatically propagates these changes to the replica Regions. Monitor the replication status to confirm successful synchronization of these changes.
The deletion process for multi-Region keys follows specific behavior patterns that are important to understand. When a primary key is scheduled for deletion, associated replica keys are deleted immediately. The primary key enters a pending deletion state with a minimum 3-day waiting period, during which the deletion can be canceled. However, if you restore the primary key by canceling its deletion, you will need to re-enable replication to recreate the replica keys in your desired Regions. After the 3-day waiting period expires, the primary key is permanently deleted and becomes unrecoverable. Note that deleting a replica key affects only that specific Region and does not impact the primary key or other replica keys.
Multi-Region key replication operates with eventual consistency. When creating new keys or making changes to existing keys, these updates might not appear immediately across all Regions. Applications should be designed to handle this eventual consistency model and not assume immediate availability of keys or key changes in replica Regions. If your application requires strong consistency, implement polling mechanisms using the GetKey API to verify that changes have been synchronized before proceeding with key operations.
Logging and monitoring
Payment Cryptography logs API activity through AWS CloudTrail, which now includes new events and attributes specific to Multi-Region key replication.
New CloudTrail event
The service logs a new event type called SynchronizeMultiRegionKey, which appears in primary and replica Regions.
Primary Region events:
Two SynchronizeMultiRegionKey events are logged in the primary Region for each replication Region defined:
To start using Multi-Region key replication in Payment Cryptography:
Determine your primary Region.
Determine your replica Regions and if you will use account-level or key-level configuration.
Create new exportable symmetric keys or update existing keys to use the Multi-Region key replication feature.
Update your applications to use the consistent key IDs across Regions.
Conclusion
The new Multi-Region key replication feature in Payment Cryptography enhances our automatic key replication capabilities, providing improved resilience and simplified management for global payment applications. This feature helps make sure your payment cryptography keys are available when and where you need them, with the flexibility to choose between account-level or key-level replication strategies.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.