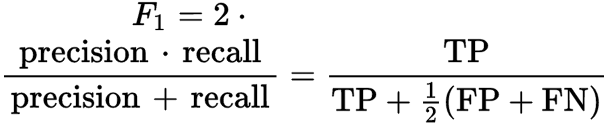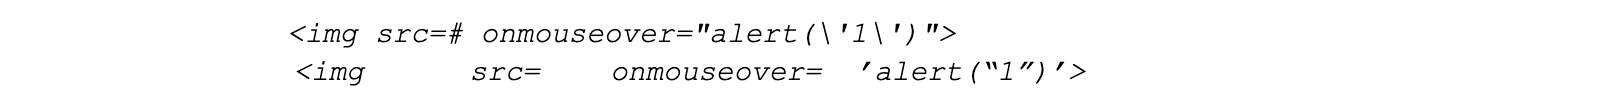Developers use AWS Step Functions, a low-code visual workflow service to build distributed applications, automate IT and business processes, and orchestrate AWS services with minimal code. Step Functions Amazon States Language (ASL) provides a set of functions known as intrinsics that perform basic data transformations.
Customers have asked for additional intrinsics to perform more data transformation tasks, such as formatting JSON strings, creating arrays, generating UUIDs, and encoding data. We have added 14 new intrinsic functions to Step Functions. This blog post examines how to use intrinsic functions to optimize and simplify your workflows.
Why use intrinsic functions?
Intrinsic functions can allow you to reduce the use of other services, such as AWS Lambda or AWS Fargate to perform basic data manipulation. This helps to reduce the amount of code and maintenance in your application.
Intrinsics can also help reduce the cost of running your workflows by decreasing the number of states, number of transitions, and total workflow duration. This allows you to focus on delivering business value, using the time spent on writing custom code for more complex processing operations rather than basic transformations.
Using intrinsic functions
Amazon States Language is a JSON-based, structured language used to define Step Functions workflows. Each state within a workflow receives a JSON input and passes a JSON output to the next state.
ASL enables developers to filter and manipulate data at various stages of a workflow state’s execution using paths. A path is a string beginning with $ that lets you identify and filter subsets of JSON text. Learn how to apply these filters to build efficient workflows with minimal state transitions.
Apply intrinsics using ASL in task states within the ResultSelector field, or in a Pass state in either the Parameters or Result field. All intrinsic functions have the prefix “States.” followed by function, as shown in the following example, which uses the new UUID intrinsic for a generating Unique Universal ID:
Reducing execution duration with intrinsic functions to lower cost
The following example shows the cost and simplicity benefits of intrinsic functions. The same payload is input to both examples. One uses intrinsic functions, the other uses a Lambda function with custom code. This is an extract from a workflow that is used in production for Serverlesspresso, a serverless ordering system for a pop-up coffee bar. It sanitizes new customer orders against menu options stored in an Amazon DynamoDB table.
This example uses a Lambda function to unmartial data from a DynamoDB table and iterates through each item, checking if the order is present and therefore valid. This Lambda function has 18 lines of code with dependencies on an SDK library for DynamoDB operations.
The improved workflow uses a Map state to iterate through, and unmarshal DynamoDB data, and then an intrinsic function within a pass state to sanitize new customer orders against the menu options. Here, the intrinsic used is the new States. ArrayContains(). It searches an array for a value.
I run both workflows 1000 times. The following image from an Amazon CloudWatch dashboard shows their average execution time and billed execution time.
The billed execution time for the workflow using intrinsics is half that of the workflow using a Lambda function (100ms vs. 200ms).
These are Express Workflows, so the total workflow cost is calculated as execution cost + duration cost x number of requests. This means the workflow that uses intrinsics costs approximately half that of the one using Lambda. This doesn’t consider the additional cost associated with running Lambda functions. Read more about building cost efficient workflows from this blog post.
Cost saving: Reducing state transitions with intrinsic functions
The previous example shows how a single intrinsic function can have a large impact on workflow duration, which directly affects the cost of running an Express Workflow. Intrinsics can also help to reduce the number of states in a workflow. This directly affects the cost of running a Standard Workflow, which is billed on the number of state transitions.
The following example runs a sentiment analysis on a text input. If it detects negative sentiment, it invokes a Lambda function to generate a UUID; it saves the information to a DynamoDB table and notifies an administrator. The workflow then pauses using the .waitFortaskToken pattern. The workflow resumes when an administrator takes action, to either allow or deny a refund. The most common path through this workflow comprises 9 state transitions.
In the following example, I remove the Lambda function, which generates a UUID. It contained the following code:
var AWS = require ('aws-sdk');
exports. handler = async (event, context) => {
    let r = Math.random().toString(36).substring(7);
    return r;
};
Instead, I use the new States.UUID() intrinsic in the ResultPath of the DetectSentimentState.
This has reduced code, resources, and states. The reduction in states from 9 to 8 means that there is one less state transition in the workflow. This has a positive effect on the cost of my Standard Workflow, which is billed by the number of state transitions. It also means that there are no longer any costs incurred for running a Lambda function.
The new intrinsic functions
Standard Workflows, Express Workflows, and synchronous Express Workflows all support the new intrinsic functions. The new intrinsics can be grouped into six categories:
With the new intrinsic functions, you can do more with workflows. The following example shows how I apply the States.ArrayLength intrinsic function in the Serverlesspresso workflow to check how many instances of the workflow are currently running, and branch accordingly.
The Step Functions List executions SDK task is first used to retrieve a list of executions for the given state machine. I use the States.ArrayLength in the ResultsSelector path to retrieve the length of the response array (total number of executions). It passes the result to a choice state as a numerical constant, allowing the workflow to branch accordingly. Serverlesspresso uses this as a graceful denial of service mechanism, preventing a new customer order when there are too many orders currently in flight.
Conclusion
AWS has added an additional 14 intrinsic functions to Step Functions. These allow you to reduce the use of other services to perform basic data manipulations. This can help reduce workflow duration, state transitions, code, and additional resource management and configuration.
Apply intrinsics using ASL in Task states within the ResultSelector field, or in a Pass state in either the Parameters or Result field. Check the AWS intrinsic functions documentation for the complete list of intrinsics.
Visit the Serverless Workflows Collection to browse the many deployable workflows to help build your serverless applications.
At Cloudflare, we are always looking for ways to make our customers’ faster and more secure. A key part of that commitment is our ongoing investment in research and development of new technologies, such as the work on our machine learning based Web Application Firewall (WAF) solution we announced during security week.
In this blog, we’ll be discussing some of the data challenges we encountered during the machine learning development process, and how we addressed them with a combination of data augmentation and generation techniques.
Let’s jump right in!
Introduction
The purpose of a WAF is to analyze the characteristics of a HTTP request and determine whether the request contains any data which may cause damage to destination server systems, or was generated by an entity with malicious intent. A WAF typically protects applications from common attack vectors such as cross-site-scripting (XSS), file inclusion and SQL injection, to name a few. These attacks can result in the loss of sensitive user data and damage to critical software infrastructure, leading to monetary loss and reputation risk, along with direct harm to customers.
How do we use machine learning for the WAF?
The Cloudflare ML solution, at a high level, trains a classifier to distinguish between various traffic types and attack vectors, such as SQLi, XSS, Command Injection, etc. based on structural or statistical properties of the content. This is achieved by performing the following operations:
We inspect the raw HTTP input and perform some number of transformations on it such as normalization, content substitutions, or de-duplication.
Decompose or partition it via some process of tokenization, generate statistical information about the content, or extract structural data.
Compute optimal internal numerical representations of the inputs via the process of training the model. The nature of these internal representations depends on the class of model and architecture.
Learn to map internal content representations against classes (XSS, SQLi or others), scores or some other target of interest.
At run-time, use previously learned representations and mappings to analyze a new input and provide the most likely label or score for it. The score ranges from 1 to 99, with 1 indicating that the request is almost certainly malicious and 99 indicating that the request is probably clean.
This reasonable starting point stumbles immediately upon a critical challenge right from the start: we need high quality labeled data, and lots of it as that has the biggest impact on model performance. Contrary to well-researched fields like image recognition, text sentiment analysis, or classification, large datasets of HTTP requests with malicious payloads embedded are difficult to get.
To make matters even harder, strict implementation requirements for a production-quality WAF restrict the complexity of our potential ML models or architectures to ones that are relatively simple and light-weight, implying that we cannot simply pave over shortcomings of the data.
Data and challenges
The selection of a dataset is likely the most difficult of all the aspects that contribute to the final set of attributes of a machine learning model. In most cases, the model is tasked with learning the distribution of the data in some statistical sense, thus choosing and curating the dataset to ensure that the desired properties of the final solution are even possible to learn is incredibly crucial! ML models are only as reliable as the data used to train them. If we train an ML model on an incomplete dataset, or on data that doesn’t accurately represent the population, predictions might be inaccurate as they will be a direct reflection of the data.
To build a strong ML WAF, a good dataset must have large volumes of heterogeneous data covering malicious samples for all attack categories, a diverse set of negative/benign samples, and samples representing a broad spectrum of obfuscation techniques.
Due to those constraints, creating a solid dataset has a number of challenges:
Privacy
Privacy requirements limit data availability and how it can be used. Cloudflare has strict privacy guidelines and does not keep all request data – it simply isn’t available, and what is available must be carefully selected, anonymised, and stripped of sensitive information.
Heterogeneity of samples
Due to the wide assortment of potential request content types and forms, finding enough benign samples is difficult. Furthermore, it is challenging to collect data that represents requests with various charsets and content-encodings. Covering all attack configurations is also important because some attacks can be inserted into essentially any kind of request (e.g. five bytes in a huge “regular” request)
Sample difficulty
We want a dataset with a good mix of attack techniques and isn’t dominated by the ones that are easily generated by tools which simply swap out constants, transform expressions through invariants, and so on (sqli-fuzzer). Additionally, the vast majority of freely available samples in the wild are fairly trivial auto-generated payloads as part of indiscriminate scanning and discovery tools. They have very similar structural and statistical characteristics. Some of them are fairly old as well and do not reflect the current software landscape. How to “grade” the sample difficulty is not immediately obvious! What’s easy to a human may not be easy for a particular preprocessor/model, and vice-versa.
Noisy labels
Label noise affects results a lot, especially when it comes to esoteric, specific, or unusual attacks which are likely to be classified as benign by rules WAF.
What’s the strategy to overcome this?
Data augmentation
In simple terms, Data Augmentation is a process of generating artificial (but realistic) data to increase the diversity of our data by studying statistical distribution of existing real-world data.
This is crucial for us because one of the biggest concerns with rules-based WAFs is false positives. False positives are a serious challenge for WAFs because the risk of accidentally filtering legitimate traffic deters users from employing very strict rulesets. Data augmentation is used to build a solution that does not rely on observing specific high-risk keywords or character sequences, but instead uses a more holistic analysis of content and context, making it considerably less likely to block legitimate requests.
There are many sequences of characters which appear almost exclusively in payloads, but are themselves not dangerous. In order to reduce false positives and improve overall performance, we focussed on generating a lot of heterogeneous negative samples to force the model to consider the structural, semantic, and statistical properties of the content when making a classification decision.
In the context of our data and use cases, data augmentation means that we mutate benign content in a variety of ways as the content will remain benign (this isn’t going to accidentally turn it into a valid payload, with probability 1). For instance, we can add random character noise, permute keywords, merge benign content together from multiple sources, and so on. Alternatively, we can seed benign content with ‘dangerous’ keywords or ngrams frequently occuring in payloads – this results in a benign sample, but ideally will teach the model not to be too sensitive to the presence of malicious tokens lacking the proper semantics and structure.
Benign content
First and foremost, generating benign content is way easier. Mutating a malicious block of content into different malicious blocks is difficult because malicious payloads have a stricter grammar and syntax than general HTTP content due to the fact that it has code, therefore they must be manipulated in a specific manner.
However, there are a few options if we want to do this in the future. Tools like sqli-fuzzer, automates the process of fuzzing a given payload by applying transformations which preserve the underlying semantics while changing the representation or adding obfuscation. Outside existing third-party tools, it’s possible to generate our own malicious payloads using various “append malicious content to non-malicious content” techniques, with the trade off that this doesn’t actually generate *new* malicious content, just puts it into a different context.
Pseudo-random noise samples
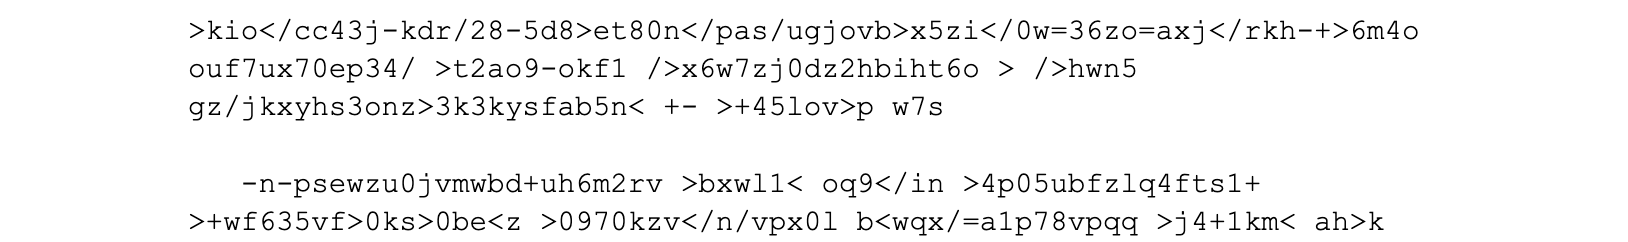
A useful approach we identified for bolstering the number of negative training samples was to generate large quantities of pseudo-random strings of increasing complexity.
The probability of any pseudo-random string (drawn from essentially any token distribution) being a valid payload or malicious attack is essentially zero, but we can build a series of token sampling distributions that make it increasingly difficult for the model to distinguish them from a real payload, and we discovered that this resulted in dramatically better performance in terms of false positive rate, robustness, and overall model properties.
This approach works by taking a collection of tokens and a probability distribution over these tokens, and independently sampling a stream of tokens from it to create our ‘sample’. Each sample length is selected from a separate discrete sample length distribution.
For an extremely simple example, we could take a token collection consisting of ASCII characters and a uniform sampling distribution:
We wouldn’t expect even a very simple model to struggle to learn that these samples are benign, but as we increase the complexity of the token collections, we can move towards much more ‘difficult’ noise examples, including elements such as: fragments of valid URIs, user agents, XML/XSLT content or even restricted language identifiers, or keywords.
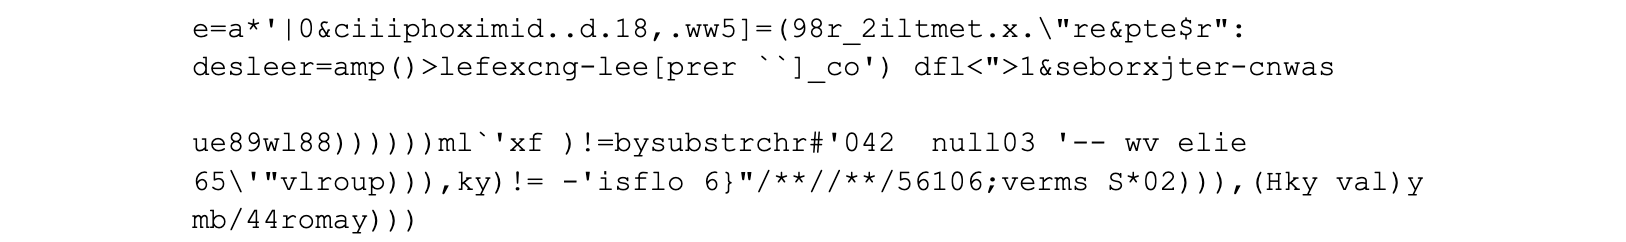
Here are some examples of more complex token collections and the kinds of random strings they produce as our negative samples:
alphanumerics, plus special characters, plus a variant of full javascript or sql keywords and (multi-character) sub-token fragments
It’s fairly straightforward to construct a suite of these noise generators of varying complexity, and targeting different types of content: JSON, XML, URIs with SQL-esque ‘noise’, and so on. As the strings get sufficiently long, the probability that they will contain at least some dangerous looking subsequences grows, so it’s also an excellent test of model robustness.
We make extensive use of noise strings to enhance the core dataset used for training and testing the model by directly training the model on increasingly difficult noise before fine-tuning on exclusively real data, appending noise of varying complexity to malicious(real) samples or benign samples to both induce and test for model robustness for padding attacks, and estimating false positive rate for certain classes of benign content.
Beyond independent sampling of random strings?
A natural extension to the above method for generating pseudo-random strings is to drop the ‘independence’ assumption for sampling tokens. This means that we’re starting to emulate the process by which real data is generated, to some extent, yielding samples with increasingly realistic local (and eventually global) structure. Some approaches for this might include a simple Markov chain, and extend all the way to state-of-the-art Large Language Models.
We experimented with using contemporary autoregressive language models trained on our corpus of real malicious payloads and found it extremely effective at generating novel payloads, as well as transforming payloads into sophisticated obfuscated representations. As the language models approached convergence on the data the likelihood of each sample being a valid payload approached 100%, allowing us to use early samples as ‘extremely strong negatives’ and the later samples as positive samples. The success of this work has suggested that deeper investigation into the use of language models for security analysis may be fruitful, not only for training classifiers, but also for creating powerful adversarial pen-testing agents.
Results summary
Let’s see a comparative summary of results and improvements, before and after the augmentation:
Model performance on evaluation metrics
The effectiveness of machine learning models for classification problems can be evaluated using a wide range of metrics, including accuracy, precision, recall, F1 Score, and others. It is important to note that in addition to using quantitative metrics, we also consider the model’s general properties and behavioral constraints. This criteria and metrics-based approach is especially important in our domain where data is inherently noisy, labels are not trustworthy, the domain of the inputs is extremely large, and hard to cover with samples.
For this post, we will concentrate on key quantitative metrics like F1 score even though we examine a variety of metrics to assess the model performance. F1 score is the weighted average (harmonic mean) of precision and recall. We can represent the F1 score with the formula:
Where,
True Positives (TP): malicious content classified correctly by the model
False Positives (FP): benign content that the model classified as malicious
True Negatives (TN): benign content classified correctly by the model
False Negatives (FN): malicious content that the model classified as benign
Since this formula takes false positives and false negatives into consideration, this score is more reliable than other metrics. There are a few methods to calculate this for multi-class problems, like Macro F1 Score, Micro F1 Score and Weighted F1 Score. Although each method has advantages and disadvantages, we obtained nearly identical results with all three methods. Below are the numbers:
Without Augmentation
With Augmentation
Class
Precision
Recall
F1 Score
Precision
Recall
F1 Score
Benign
0.69
0.17
0.27
0.98
1.00
0.99
SQLi
0.77
0.96
0.85
1.00
1.00
1.00
XSS
0.56
0.94
0.70
1.00
0.98
0.99
Total(Micro Average)
0.67
0.99
Total(Macro Average)
0.67
0.69
0.61
0.99
0.99
0.99
Total(Weighted Average)
0.68
0.67
0.60
0.99
0.99
0.99
The important takeaway is that the range of this F1 score is best at 1 and worst at 0.
The model after augmentation appears to have similar precision and recall with good overall performance, as indicated by a value of 0.99 after augmentation, compared to 0.61 for Macro F1.
So far in the results summary, we’ve only discussed F1 Score; however, there are other improvements in characteristics that we’ve observed in the model that are listed below:
False positive characteristics
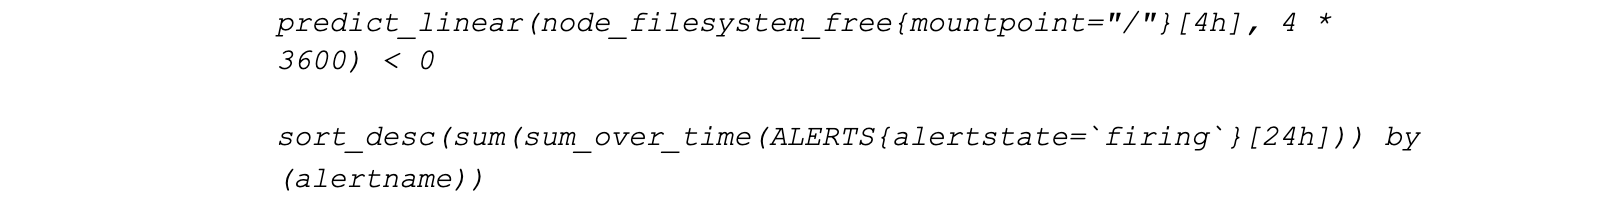
Estimated false positive rate reduced by approximately 80% on test data sets. There are significantly fewer false positives involving PromQL and other SQL-structured analogues. PromQL examples result in high scores and are classified correctly:
Today, the only major category of false positives are literal SQL or JavaScript files.
General false positive rate on noise from JSON-esque, XML/SOAP-esque, and SQL-esque content-generators reduced to about a 1/100,000 rate from about 1/50 to 1/1.
True positive characteristics
True positive rate for highly fuzzed content is vastly improved. Models trained solely on real data were easily bypassed by advanced fuzzing tools, whereas models trained on real plus augmented data are extremely resistant, with many payloads receiving higher risk scores as fuzzing increases. Examples:
These yield approximately same scores as they are a result of only a few byte alterations
Proportion of client-provided test sets that primarily contain payloads not blocked by rules-waf for XSS/SQLi successfully classified is about 97.5% (with the remaining 2.5% being arguable) up from about 91%.
Padding a payload with almost any amount of ASCII, JSON-esque, special-characters, or other content will not reduce the risk score substantially. Due to the addition of hard noise long length augmented training samples, even a six byte payload in a 100 kilobyte string will be caught. Examples:
They both generate similar scores even though the latter has junk padding around the payload.
Execution performance
Runtime characteristics are unchanged for inference.
On top of that, we validated the model against the Cloudflare’s highly mature signature-based WAF and confirmed that machine learning WAF performs comparable to signature WAF, with the ML WAF demonstrating its strength particularly in cases of correctly handling highly obfuscated or irregularly fuzzed content (as well as avoiding some rules-based engine false positives). Finally, we were able to conclude that augmentation helps in improving the model performance and induce the right set of properties.
Conclusion
We built a machine learning powered WAF, with the substantial challenge to gather a diversified training set, given constraints to avoid sensitive real customer data for privacy and regulatory considerations. To create a broader and diversified dataset without requiring vast amounts of sensitive data, we used techniques such as fuzzing, data augmentation, and synthetic data generation. This allowed us to improve the solution’s false positive robustness and overall model performance.
Furthermore, these techniques reduced the time complexity required to retrieve/clean real data, and helped induce the correct model behavior. In the future, we intend to investigate autoregressive language models to generate synthetic pseudo-valid payloads.
The 6.0-rc4 kernel prepatch is out for
testing. “We’re up to rc4, and things mostly still look fairly
normal“.
Beyond the usual fixes, 6.0-rc4 includes one feature change: a hook to allow
security modules to control access to the io_uring command pass-through
mechanism. See this article for the
background behind this late-arriving change.
Peter Eckersley, one of the original founders of the Let’s Encrypt non-profit TLS certificate authority, has died suddenly, as reported by Seth Schoen:
Peter was the leader of EFF’s contributions to Let’s Encrypt and ACME over the course of several years during which these technologies turned from a wild idea into an important part of Internet infrastructure. He also took a lot of initiative in coalescing the EFF, Mozilla, and University of Michigan teams into a single team and a single project. He later served on the initial board of directors of the Internet Security Research Group.
[…]
Toward the end of his life, Peter focused his career on ethics and safety of artificial intelligence, and he founded the AI Objectives Institute to examine the concrete parallels he saw between surprising and undesirable outcomes that can emerge within economies and those that can emerge in machine learning systems.
We have blocked Kiwifarms. Visitors to any of the Kiwifarms sites that use any of Cloudflare’s services will see a Cloudflare block page and a link to this post. Kiwifarms may move their sites to other providers and, in doing so, come back online, but we have taken steps to block their content from being accessed through our infrastructure.
This is an extraordinary decision for us to make and, given Cloudflare’s role as an Internet infrastructure provider, a dangerous one that we are not comfortable with. However, the rhetoric on the Kiwifarms site and specific, targeted threats have escalated over the last 48 hours to the point that we believe there is an unprecedented emergency and immediate threat to human life unlike we have previously seen from Kiwifarms or any other customer before.
Escalating threats
Kiwifarms has frequently been host to revolting content. Revolting content alone does not create an emergency situation that necessitates the action we are taking today. Beginning approximately two weeks ago, a pressure campaign started with the goal to deplatform Kiwifarms. That pressure campaign targeted Cloudflare as well as other providers utilized by the site.
Cloudflare provides security services to Kiwifarms, protecting them from DDoS and other cyberattacks. We have never been their hosting provider. As we outlined last Wednesday, we do not believe that terminating security services is appropriate, even to revolting content. In a law-respecting world, the answer to even illegal content is not to use other illegal means like DDoS attacks to silence it.
We are also not taking this action directly because of the pressure campaign. While we have empathy for its organizers, we are committed as a security provider to protecting our customers even when they run deeply afoul of popular opinion or even our own morals. The policy we articulated last Wednesday remains our policy. We continue to believe that the best way to relegate cyberattacks to the dustbin of history is to give everyone the tools to prevent them.
However, as the pressure campaign escalated, so did the rhetoric on the Kiwifarms site. Feeling attacked, users of the site became even more aggressive. Over the last two weeks, we have proactively reached out to law enforcement in multiple jurisdictions highlighting what we believe are potential criminal acts and imminent threats to human life that were posted to the site.
Legal process
While law enforcement in these areas are working to investigate what we and others reported, unfortunately the process is moving more slowly than the escalating risk. While we believe that in every other situation we have faced — including the Daily Stormer and 8chan — it would have been appropriate as an infrastructure provider for us to wait for legal process, in this case the imminent and emergency threat to human life which continues to escalate causes us to take this action.
Hard cases make bad law. This is a hard case and we would caution anyone from seeing it as setting precedent. The policies we articulated last Wednesday remain our policies. For an infrastructure provider like Cloudflare, legal process is still the correct way to deal with revolting and potentially illegal content online.
But we need a mechanism when there is an emergency threat to human life for infrastructure providers to work expediently with legal authorities in order to ensure the decisions we make are grounded in due process. Unfortunately, that mechanism does not exist and so we are making this uncomfortable emergency decision alone.
Not the end
Finally, we are aware and concerned that our action may only fan the flames of this emergency. Kiwifarms itself will most likely find other infrastructure that allows them to come back online, as the Daily Stormer and 8chan did themselves after we terminated them. And, even if they don’t, the individuals that used the site to increasingly terrorize will feel even more isolated and attacked and may lash out further. There is real risk that by taking this action today we may have further heightened the emergency.
We will continue to work proactively with law enforcement to help with their investigations into the site and the individuals who have posted what may be illegal content to it. And we recognize that while our blocking Kiwifarms temporarily addresses the situation, it by no means solves the underlying problem. That solution will require much more work across society. We are hopeful that our action today will help provoke conversations toward addressing the larger problem. And we stand ready to participate in that conversation.
Arti is a reimplementation of the Tor server in Rust; version 1.0.0 has
just been released and proclaimed ready for production use.
When we defined our set of milestones, we defined Arti 1.0.0 as
“ready for production use”: You should be able to use it in the
real world, to get a similar degree of privacy, usability, and
stability to what you would with a C client Tor. The APIs should be
(more or less) stable for embedders.
We believe we have achieved this. You can now use arti
proxy to
connect to the Tor network to anonymize your network connections.
This week Metasploit has a new ICPR Certificate Management module from Oliver Lyak and our very own Spencer McIntyre, which can be utilized for issuing certificates via Active Directory Certificate Services. It has the capability to issue certificates which is useful in a few contexts including persistence, ESC1 and as a primitive necessary for exploiting CVE-2022-26923. Resulting in the PFX certificate file being stored to loot and is encrypted using a blank password.
ManageEngine ADAudit Plus and DataSecurity Plus Xnode enum
Another addition thanks to Erik Wynter and Sahil Dhar, that brings two new auxiliary/gather modules and docs that take advantage of default Xnode credentials (CVE-2020–11532) in order to enumerate active directory information and other sensitive data via the DataEngine Xnode server (Xnode). Because both modules rely on the same code to interact with Xnode, this change also adds a mixin at lib/msf/core/auxiliary/manageengine_xnode that is leveraged by both modules (plus by a third module that will be part of a separate PR). Both modules also come with configuration files to determine what data will be enumerated from Xnode. The PR contains even more information on the vulnerable systems and extensive notes!
New module content (5)
ICPR Certificate Management by Oliver Lyak and Spencer McIntyre – This adds a module for issuing certificates via Active Directory Certificate Services, which is useful in a few contexts including persistence and for some specific exploits. The resulting PFX certificate file is stored to the loot and is encrypted using a blank password.
ManageEngine ADAudit Plus Xnode Enumeration by Erik Wynter and Sahil Dhar, which exploits CVE-2020-11532 – Two new auxiliary/gather modules have been added that take advantage of default Xnode credentials, aka CVE-2020–11532, in order to enumerate Active Directory information and other sensitive data via the DataEngine Xnode server. Additionally, a new library has been added to provide reusable functionality for interacting with Xnode servers.
ManageEngine DataSecurity Plus Xnode Enumeration by Erik Wynter and Sahil Dhar, which exploits CVE-2020-11532 – Two new auxiliary/gather modules have been added that take advantage of default Xnode credentials, a.k.a CVE-2020–11532, in order to enumerate Active Directory information and other sensitive data via the DataEngine Xnode server. Additionally, a new library has been added to provide reusable functionality for interacting with Xnode servers.
Zyxel Firewall SUID Binary Privilege Escalation by jbaines-r7, which exploits CVE-2022-30526 – This adds an LPE exploit for Zyxel Firewalls that can allow a user to escalate themselves to root. The vulnerability is identified as CVE-2022-30526 and is due to a suid binary that allows any user to copy files with root permissions.
CVE-2022-30190 AKA Follina by bwatters-r7 – This updates the exploit for CVE-2022-30190 (A.K.A Follina) to support generating RTF exploit documents. RTF documents are helpful for not only being another exploit vector, but they will trigger the payload execution when viewed by Explorer’s preview tab without needing user interaction to enable editing functionality.
Enhancements and features (4)
#16746 from adfoster-r7 – This updates the MSSQL login scanner to catch exceptions and continue running.
#16900 from bcoles – This adds a new #kill_process method that supports shell, PowerShell, and Meterpreter sessions on different platforms.
#16903 from bcoles – This cleans up the enum_shares post modules and adds support for shell sessions.
#16959 from adfoster-r7 – The time command has been updated with the --cpu and --memory profiler options to allow users to get memory and CPU usage profiles when running a command inside msfconsole.
Bugs fixed (5)
#16750 from bojanisc – This updates the exploit/multi/http/jenkins_script_console module to use the decoder from the java.util.Base64 class in place of the now-deprecated decoder from the sun.misc.BASE64Decoder class, enabling exploitation of newer Jenkins versions.
#16869 from bcoles – This fixes an issue in the file_remote_digestmd5() and file_remote_digestsha1() methods where read_file() would return an error message instead of the remote file contents. Additionally, the file_remote_digest* methods now support more session types, and they have a new util option that allows the user to perform the hashing on the remote host instead of downloading the remote file and performing the hashing locally.
#16918 from rbowes-r7 – A bug has been fixed in the module for CVE-2022-30333 whereby if the server responded with a 200 OK response, the module would keep trying to trigger the payload. This would lead to multiple sessions being returned when only one was desired.
#16920 from zeroSteiner – A typo has been fixed in _msfvenom that prevented ZSH autocompletion from working when using the --arch argument with msfvenom.
#16955 from gwillcox-r7 – This fixes an issue in the LDAP query module that would cause issues if the user queried for a field that was populated with binary data.
Get it
As always, you can update to the latest Metasploit Framework with msfupdate
and you can get more details on the changes since the last blog post from
GitHub:
[Pull Requests 6.2.14…6.2.15][prs-landed]
[Full diff 6.2.14…6.2.15][diff]
If you are a git user, you can clone the [Metasploit Framework repo][repo] (master branch) for the latest.
To install fresh without using git, you can use the open-source-only [Nightly Installers][nightly] or the
There are a lot of pros and cons that go along with using the old, reliable LTO system for your backups. And while the medium still has many adherents, there is a growing movement of folks looking to move beyond magnetic tape, a form of storage technology that has been around since 1928. Technically, it’s the same age as sliced bread.
Those working in IT already know the benefits of migrating from LTO to cloud storage, which include everything from nearly universal ease of access to reduced maintenance, but those who hold the company’s pursestrings might still need convincing. Some organizations delay making a move because of misconceptions about the cost, inconvenience, risk, and security, but they may not have all the details. Let’s explore five top misconceptions about migrating from tape so you can help your team make an informed decision.
Misconception #1 – Total Cost of Ownership is Higher in the Cloud
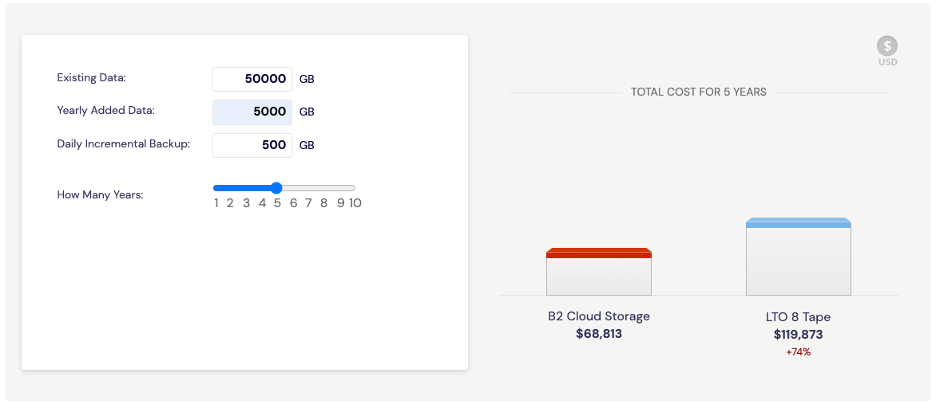
The first misconception is that moving from a tape-based backup solution to cloud storage is expensive. Using our LTO vs. B2 Cloud Storage calculator, you can enter the amount of existing data you have, the amount of data you add yearly, and your daily incremental data to determine the actual cost savings.
For example, say you have 50TB of existing data, you add 5TB more every year, and your daily incremental backup data is 500GB. If that were the case, you could expect to pay almost 75% less backing up with cloud storage versus tape. The calculator also includes details about the assumptions we used in the computations so you can adjust accordingly. These assumptions include the LTO Backup Model, Data Compression Ratio and Data Retention Policy, as well as a handful of others you can dig into on your own if you’d like to fine tune the math.
Misconception #2 – Migration Costs are Impossible to Manage
We have shown how much more affordable it is to store on the cloud vs. on tape, but what about the costs of moving all of your data? Everyone with a frequently accessed data archive and especially those serving data to end users live in fear of large egress fees. Understandably the idea of paying egress fees for ALL of their data at once can be paralyzing. There is one service available today that pays for your data migration—egress fees, transfer costs, administration, all of it.
The new Universal Data Migration (UDM) service covers data migration fees for customers in US, Canada, Europe storing more than 10TB—including any legacy provider egress fees. The service offers a suite of tools and resources to make moving your data over to cloud storage a breeze, including high speed processes for reading tape media (reel cassettes and cartridges) and transferring directly to Backblaze B2 via a high-speed data connection. This all comes with full solution engineer support throughout the process and beyond. Data is transferred quickly and securely within days, not weeks.
Short story: Even if it might feel like it some days, your data does not have to be held hostage by egress expenses. Migration can be the opposite of a “killer”–it can open your budget for other investments and free your teams to access the data they need whenever they need it.
Misconception #3 – Cloud Storage Is a Security Risk
A topic on everyone’s minds these days is security. It’s reasonable to worry about risks when transitioning from tapes stored on-premises or off-site to the cloud. You can see the tapes on site; they’re disconnected from the internet and locked in a storage space on your property. When it comes to cybercriminals accessing data, you’re breathing easy. Statistics on data breaches and ransomware show that businesses of every size are at risk when it comes to cyberattacks, so this is an understandable stance. But when you look at the big picture, the cloud can offer greater peace of mind across a wide range of risks:
Cut Risk by Tiering Data Off Site: Cybercrime is certainly a huge threat, so it’s wise to keep it front of mind in your planning. There are a number of other risk factors that deserve equal consideration, however. Whether you live in an area prone to natural disasters, are headquartered in an older building, or just have bad luck, getting a copy of your data offsite is essential to ensuring you can recover from most disasters.
Apply Object Lock for Virtual Air Gapping: Air gaps used to be the big divider between cloud and tape on the security front. But setting immutability through Object Lock means you can set a virtual air gap on all of your cloud data. This functionality is available through Veeam, MSP 360, and a number of other leading backup management software providers. You don’t have to rely on tape to attain object lock.
Boost Security without Burdening IT: Cloud storage providers’ full time job is maintaining the durability of the data they hold—they focus 24/7 on maintenance and upkeep so you don’t have to worry about whether your hardware and software are up to date and properly maintained. No need to sweat security updates, patches, or dealing with alerts. That’s your provider’s problem.
Misconception #4 – It’s All or Nothing with Data Migration
For certain industries, regulations require that certain data sets stay on-site. In the past, managing some data on-site and some in the cloud was just too much of a hassle. But hybrid services have come a long way toward making the process smoother and more efficient.
For all of your data that doesn’t have to stay on-site, you could start using cloud storage for daily incremental backups today, while keeping your tape system in place for older archived data. Not only would this save you time not worrying about as many tapes, but you can also restore the cloud-based files instantly if you need to.
Using software from StarWind VTL or Archiware P5, you can start backing up to the cloud instantly and make the job of migrating more manageable.
The Hybrid Approach
If you’re not able to go in on the all-in cloud approach right away, you may want to continue to keep some archived data on tape and move over any current data that is more critical. A hybrid system gives you options and allows you to make the transition on your schedule.
Some of the ways companies execute the hybrid model are:
Date Hybrid: Pick a cut-off date; everything after that date is stored in cloud storage and everything before stays on tape.
Classic Hybrid: Full backups remain on tape and incremental data is stored in the cloud.
Type Hybrid: You might store different data types on tape and other types in the cloud. For example, perhaps you store employee files on tape and customer data in cloud storage.
Regardless of how you choose to break it up, the hybrid model makes it faster and easier to migrate.
Misconception #5 – The Costs Outweigh the Benefits
If you’re going to go through the process of migrating your data from LTO to the cloud—even though we’ve shown it to be fairly painless—you want to make sure there’s an upside, right?
Let’s start with the simple ease of access. With tape storage, the nature of physical media means that access is limited by its nature. You have to be on premises to locate the data you need (no small feat if you have a catalog of tapes to sort through).
By putting all that data in the cloud, you enable instant access to anyone in your organization with the right provisions. This shifts hours of burden from your IT department, helping the organization get more out of the resources and infrastructure they already have.
Bonus Pro-Tip: Use a “Cheat Sheet” or Checklist to Convince Your CFO or COO
When you pitch the idea of migrating from tape to cloud storage to your CFO or COO, you can allay their fears by presenting them with a cheat sheet or checklist that proactively addresses any concerns they might have.
Some things to include in your cheat sheet are basically what we’ve outlined above: First, that cloud storage is not more expensive than tape; it actually saves you money. Second, using a hybrid model, you can move your data over conveniently on your own time. There is no cost to you to migrate your data using our UDM service, and your data is fully protected against loss and secured by Object Lock to keep it safe and sound in the cloud.
Migration Success Stories
Check out these tape migration success stories to help you decide if this solution is right for you.
Kings County, CA
Kings County, California, experienced a natural disaster destroying their tapes and tape drive, prompting an $80,000 price tag to continue backing up critical county data like HIPAA records and legal information. John Devlin, CIO of Kings County, decided it was time for a change. His plan was to move away from capital expenditures (tapes and tape drives) to operating expenses like cloud storage and backup software. After much debate, Kings County decided on Veeam Software paired with Backblaze B2 Cloud Storage for its backup solution, and it’s been smooth sailing ever since!
Austin City Limits
Austin City Limits is a public TV program that has stored more than 4,000 hours of priceless live music performances on tape. As those tapes were rapidly beginning to deteriorate, the company opted to transfer recordings to Backblaze B2 Cloud Storage for immediate and ongoing archiving with real-time, hot access. Utilizing a Backblaze Fireball rapid data ingest tool, they were able to securely back up hours of footage without tying up bandwidth. Thanks to their quick actions, irreplaceable performances from Johnny Cash, Stevie Ray Vaughan and The Foo Fighters are now preserved for posterity.
In Summary
So, we’ve covered that moving your backups to a storage cloud can save your organization time and money, is a fairly painless process to undertake, doesn’t present a higher security risk, and creates important geo-redundancies that represent best practices. Hopefully, we’ve helped clear up those misconceptions and we’ve helped you decide whether migrating from tape to cloud storage makes sense for your business.
Can you find out what your laptop is doing during its boot with Zabbix? Of course, you can!
By day, I am a monitoring technical lead in a global cyber security company. By night, I monitor my home with Zabbix & Grafana and do some weird experiments with them. Welcome to my weekly blog about this project.
This time I was originally planning to write about how to monitor yet another device with Zabbix, but as in today’s world deliveries seem to take a long time, I’ll blog about something else — Zabbix and syslog collection.
Zabbix as syslog platform?
You might not think of Zabbix as of a syslog platform, as there are specialized tools for that, providing much more functionality for log management than Zabbix ever could. However, sending syslog information to Zabbix can be very useful. In bigger environments, sending everything to it might be overkill and too taxing, so please, filter with care and consider the log retention period, but at home with a very low logging rate, this can be handy.
Logs? How and why?
At my home network, a Raspberry Pi 4 is running a Zabbix server, among other software. One of the roles of my cool little Raspberry is that it acts as a centralized syslog server. I have configured my home router, MacBook, and one more laptop to send their syslog to rsyslogd running on my Raspberry.
Then, on Zabbix, I have an item configured to keep an eye on the centralized log file the events are flowing into.
This way, I can see all kinds of events happening on those devices via Zabbix, and create appropriate triggers if something worth mentioning gets logged. Inspecting the syslog with the Zabbix Plain text widget, it’s shown absolutely everything, and well, that view probably contains just noise.
Adding details
However, if you start searching for whatever you would need to know about, then you of course can search for content. Let’s see what my MacBook has automatically updated lately:
I can then add a trigger that would log the time when something got installed or updated. It’s in no way a replacement for a proper log management solution, but for Super Important Targets something like this could be very useful, as you could catch any looming issues via Zabbix immediately, too.
Likewise, I can see what my Linux laptop has been doing:
In my configuration, absolutely everything gets sent to Zabbix, so the syslog entries from the devices are coming in starting from the moment the devices have their network & syslog services up, and they will stop coming when the syslog service stops during a shutdown.
Here’s the Linux laptop starting up:
MacBook also sends its events to syslog during OS updates/startup/shutdown, but it’s been so long since I last restarted my Mac that my Zabbix does not have the logs for that period of time anymore, and I don’t want to restart my MacBook (which I’m using to type this blog entry) just to get a screenshot from its boot sequence.
Hopefully, my new gadget will arrive soon, so I can then finally blog about that.
I have been working at Forcepoint since 2014 and in addition to monitoring addict, I am a log addict, too. — Janne Pikkarainen
This post was originally published on the author’s LinkedIn account.
This is an adapted transcript of a talk we gave at Monitorama 2022. You can find the slides with presenter’s notes here and video here.
When a request at Cloudflare throws an error, information gets logged in our requests_error pipeline. The error logs are used to help troubleshoot customer-specific or network-wide issues.
We, Site Reliability Engineers (SREs), manage the logging platform. We have been running Elasticsearch clusters for many years and during these years, the log volume has increased drastically. With the log volume increase, we started facing a few issues. Slow query performance and high resource consumption to list a few. We aimed to improve the log consumer’s experience by improving query performance and providing cost-effective solutions for storing logs. This blog post discusses challenges with logging pipelines and how we designed the new architecture to make it faster and cost-efficient.
Before we dive into challenges in maintaining the logging pipelines, let us look at the characteristics of logs.
Characteristics of logs
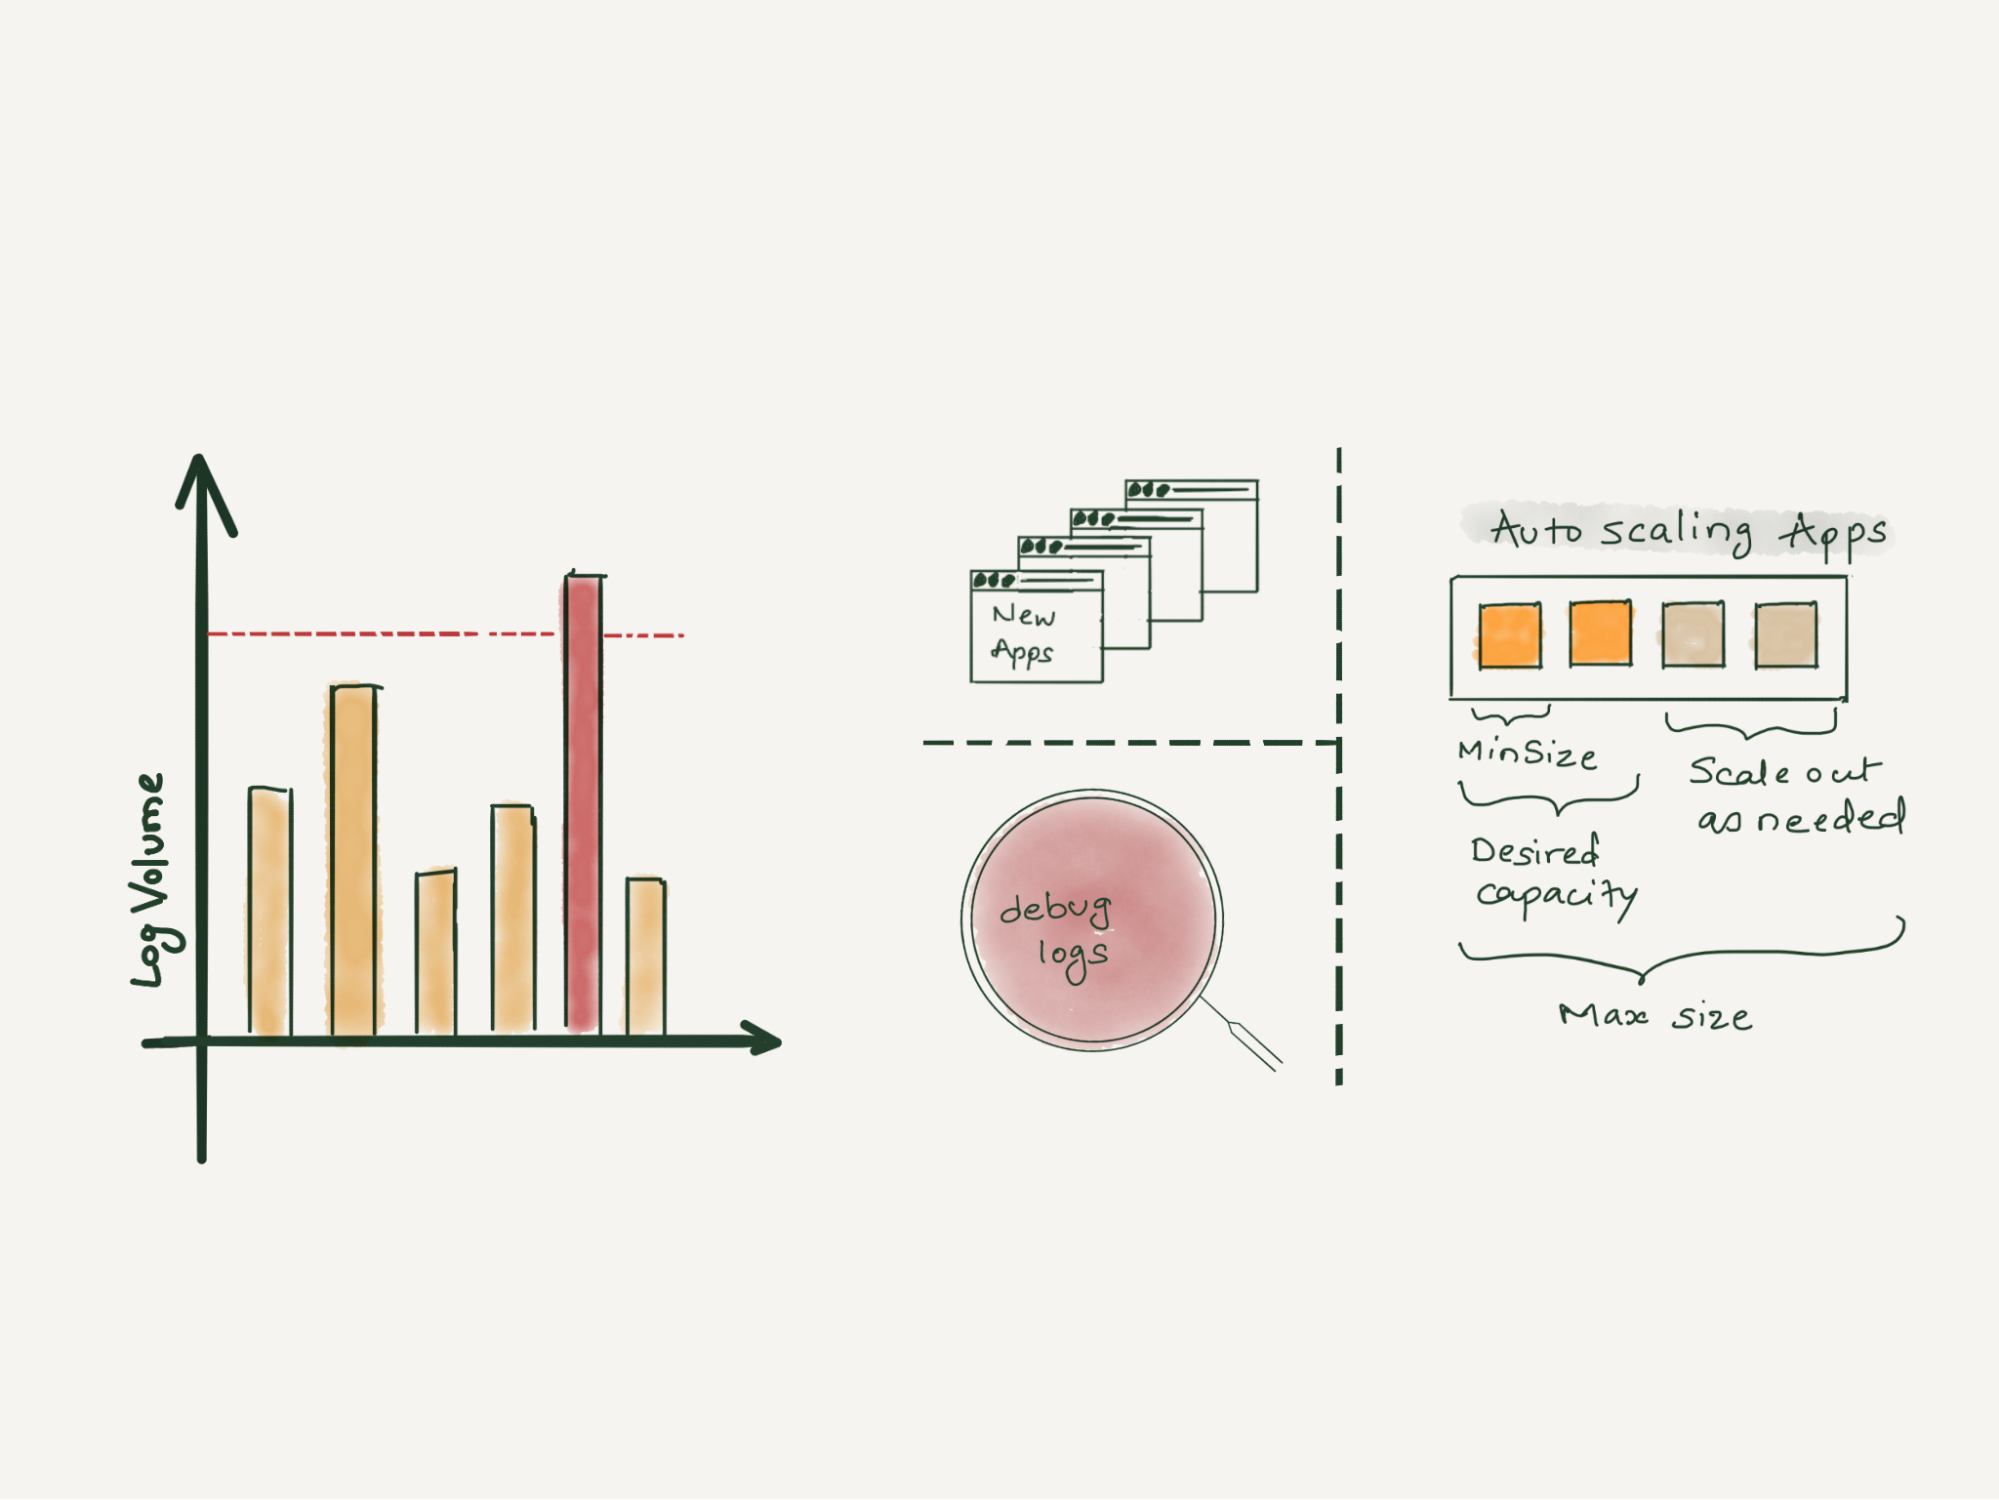
Unpredictable – In today’s world, where there are tons of microservices, the amount of logs a centralized logging system will receive is very unpredictable. There are various reasons why capacity estimation of log volume is so difficult. Primarily because new applications get deployed to production continuously, existing applications are automatically scaled up or down to handle business demands or sometimes application owners enable debug log levels and forget to turn it off.
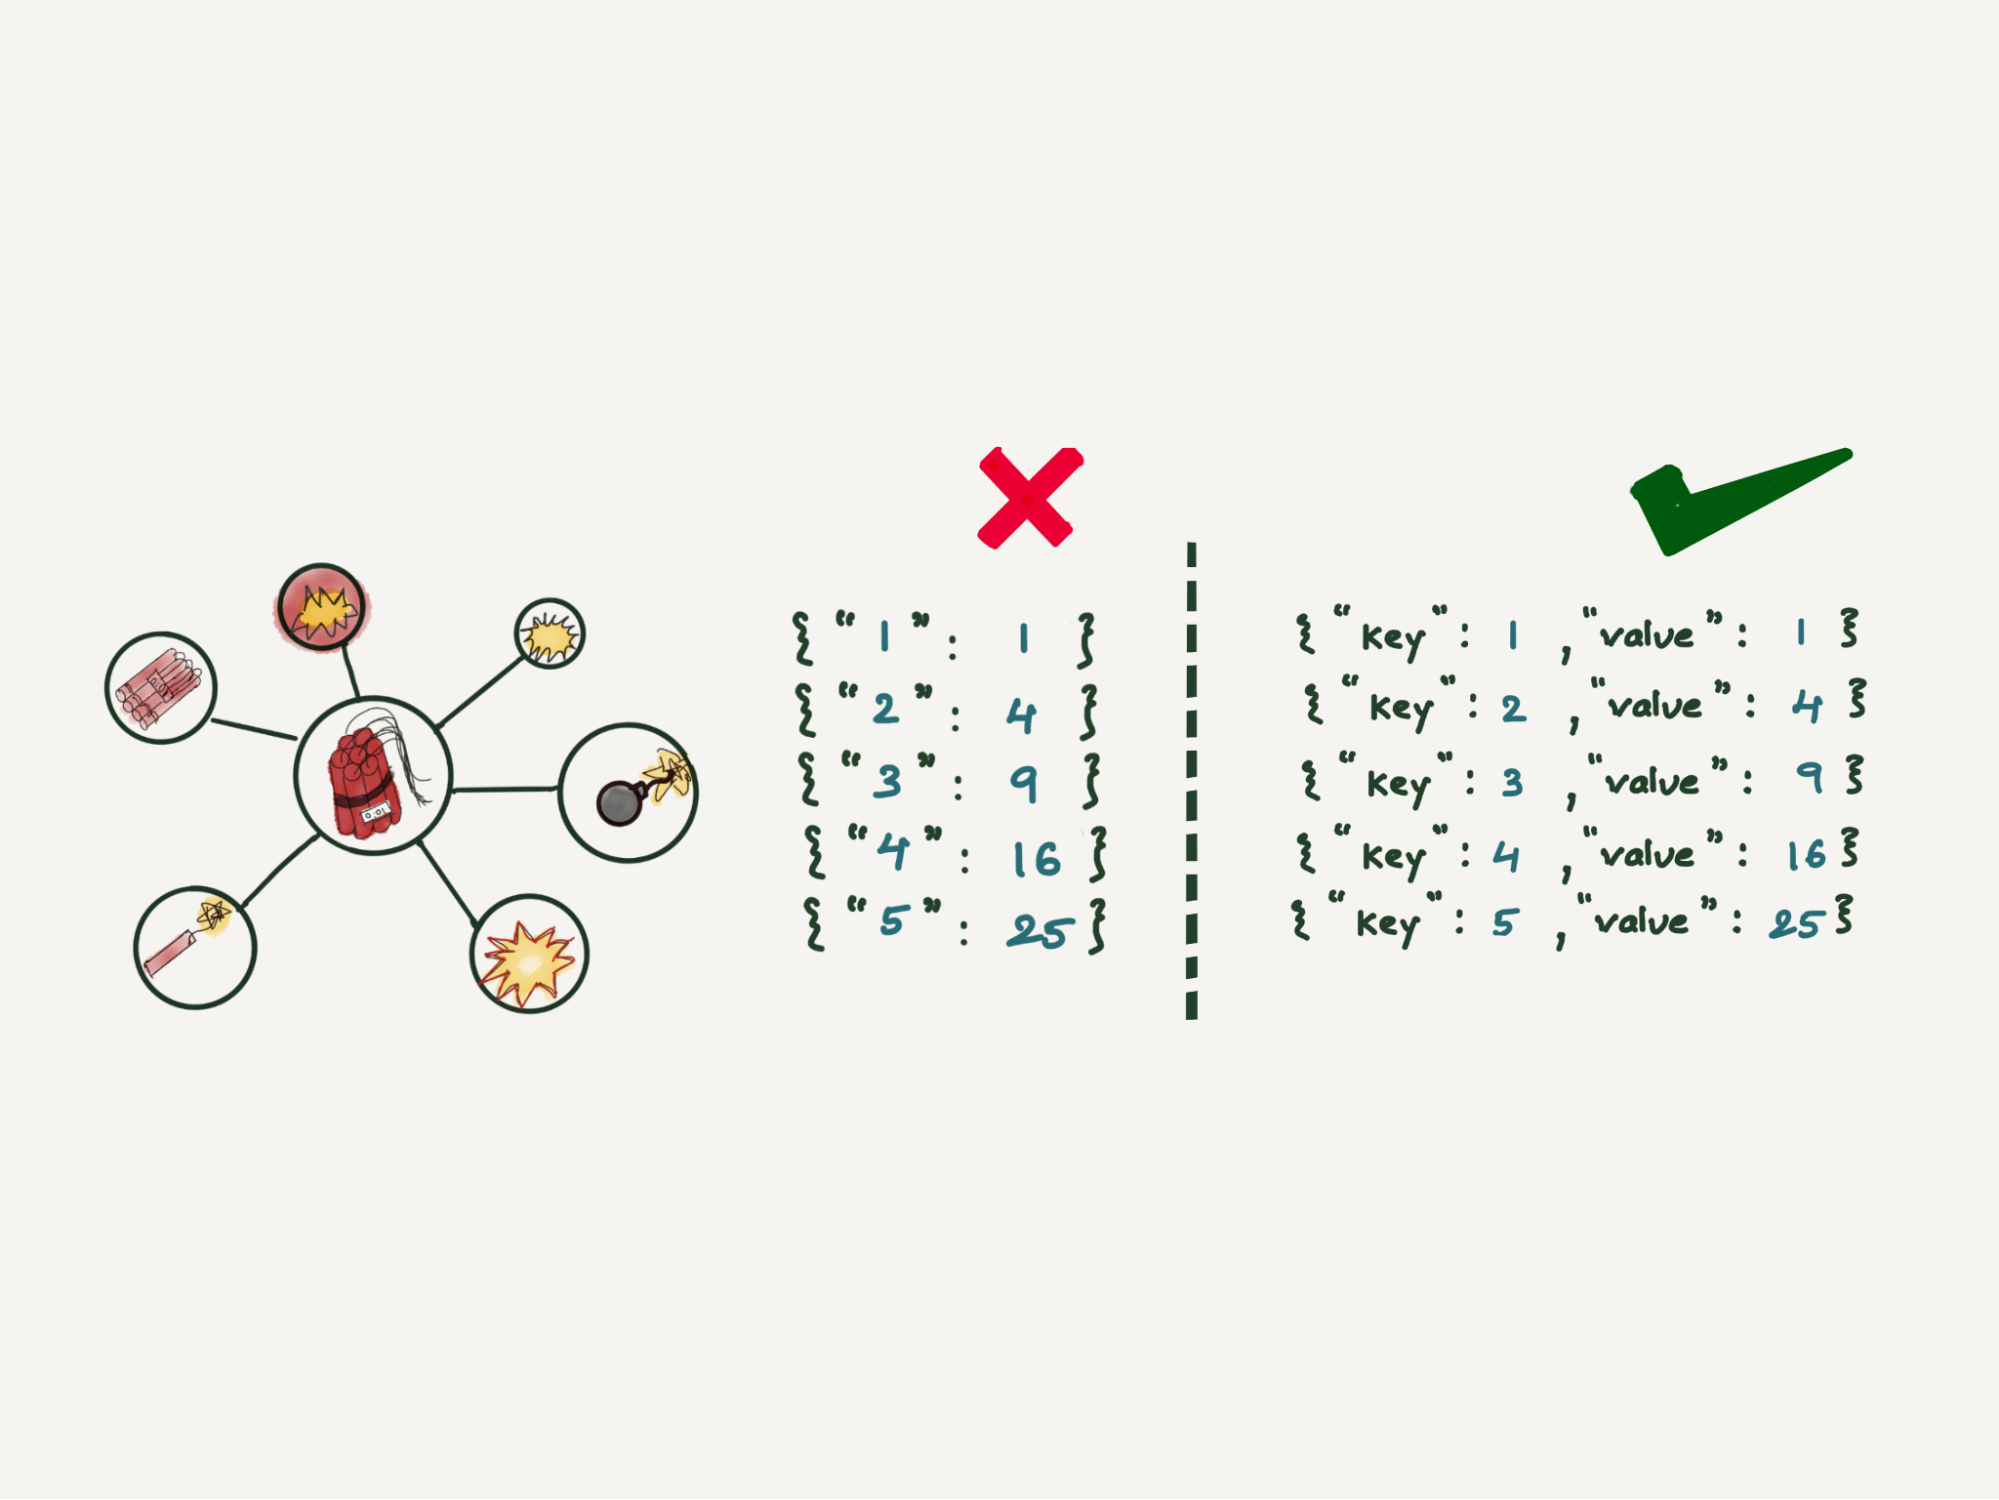
Semi-structured – Every application adopts a different logging format. Some are represented in plain-text and others use JSON. The timestamp field within these log lines also varies. Multi-line exceptions and stack traces make them even more unstructured. Such logs add extra resource overhead, requiring additional data parsing and mangling.
Contextual – For debugging issues, often contextual information is required, that is, logs before and after an event happened. A single logline hardly helps, generally, it’s the group of loglines that helps in building the context. Also, we often need to correlate the logs from multiple applications to draw the full picture. Hence it’s essential to preserve the order in which logs get populated at the source.
Write-heavy – Any centralized logging system is write-intensive. More than 99% of logs that are written, are never read. They occupy space for some time and eventually get purged by the retention policies. The remaining less than 1% of the logs that are read are very important and we can’t afford to miss them.
Logging pipeline
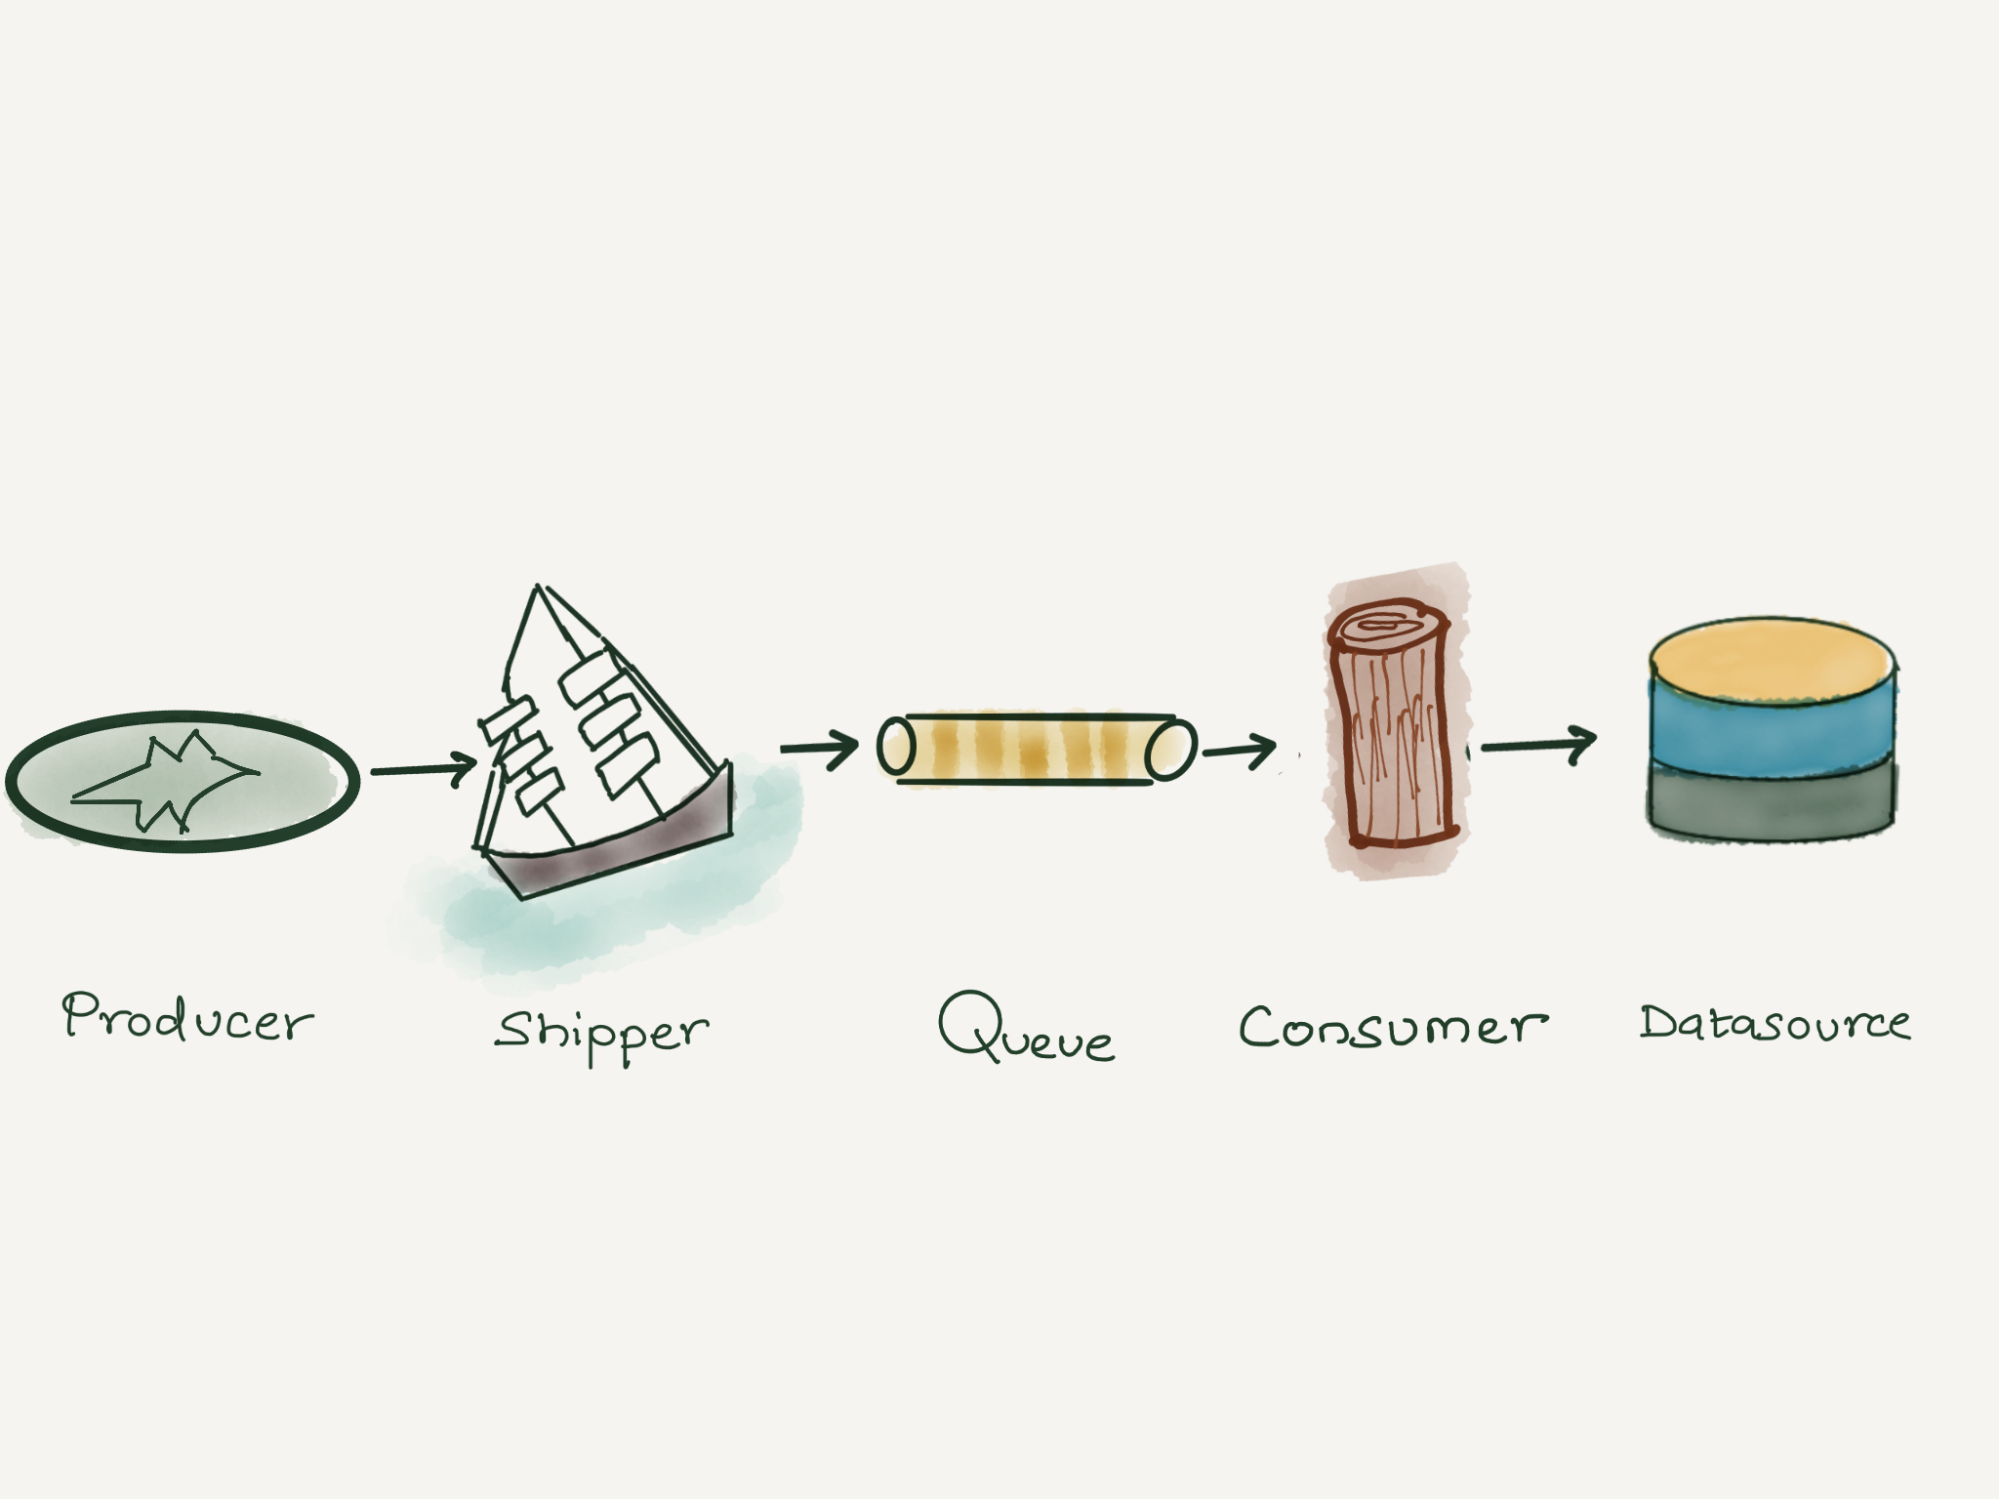
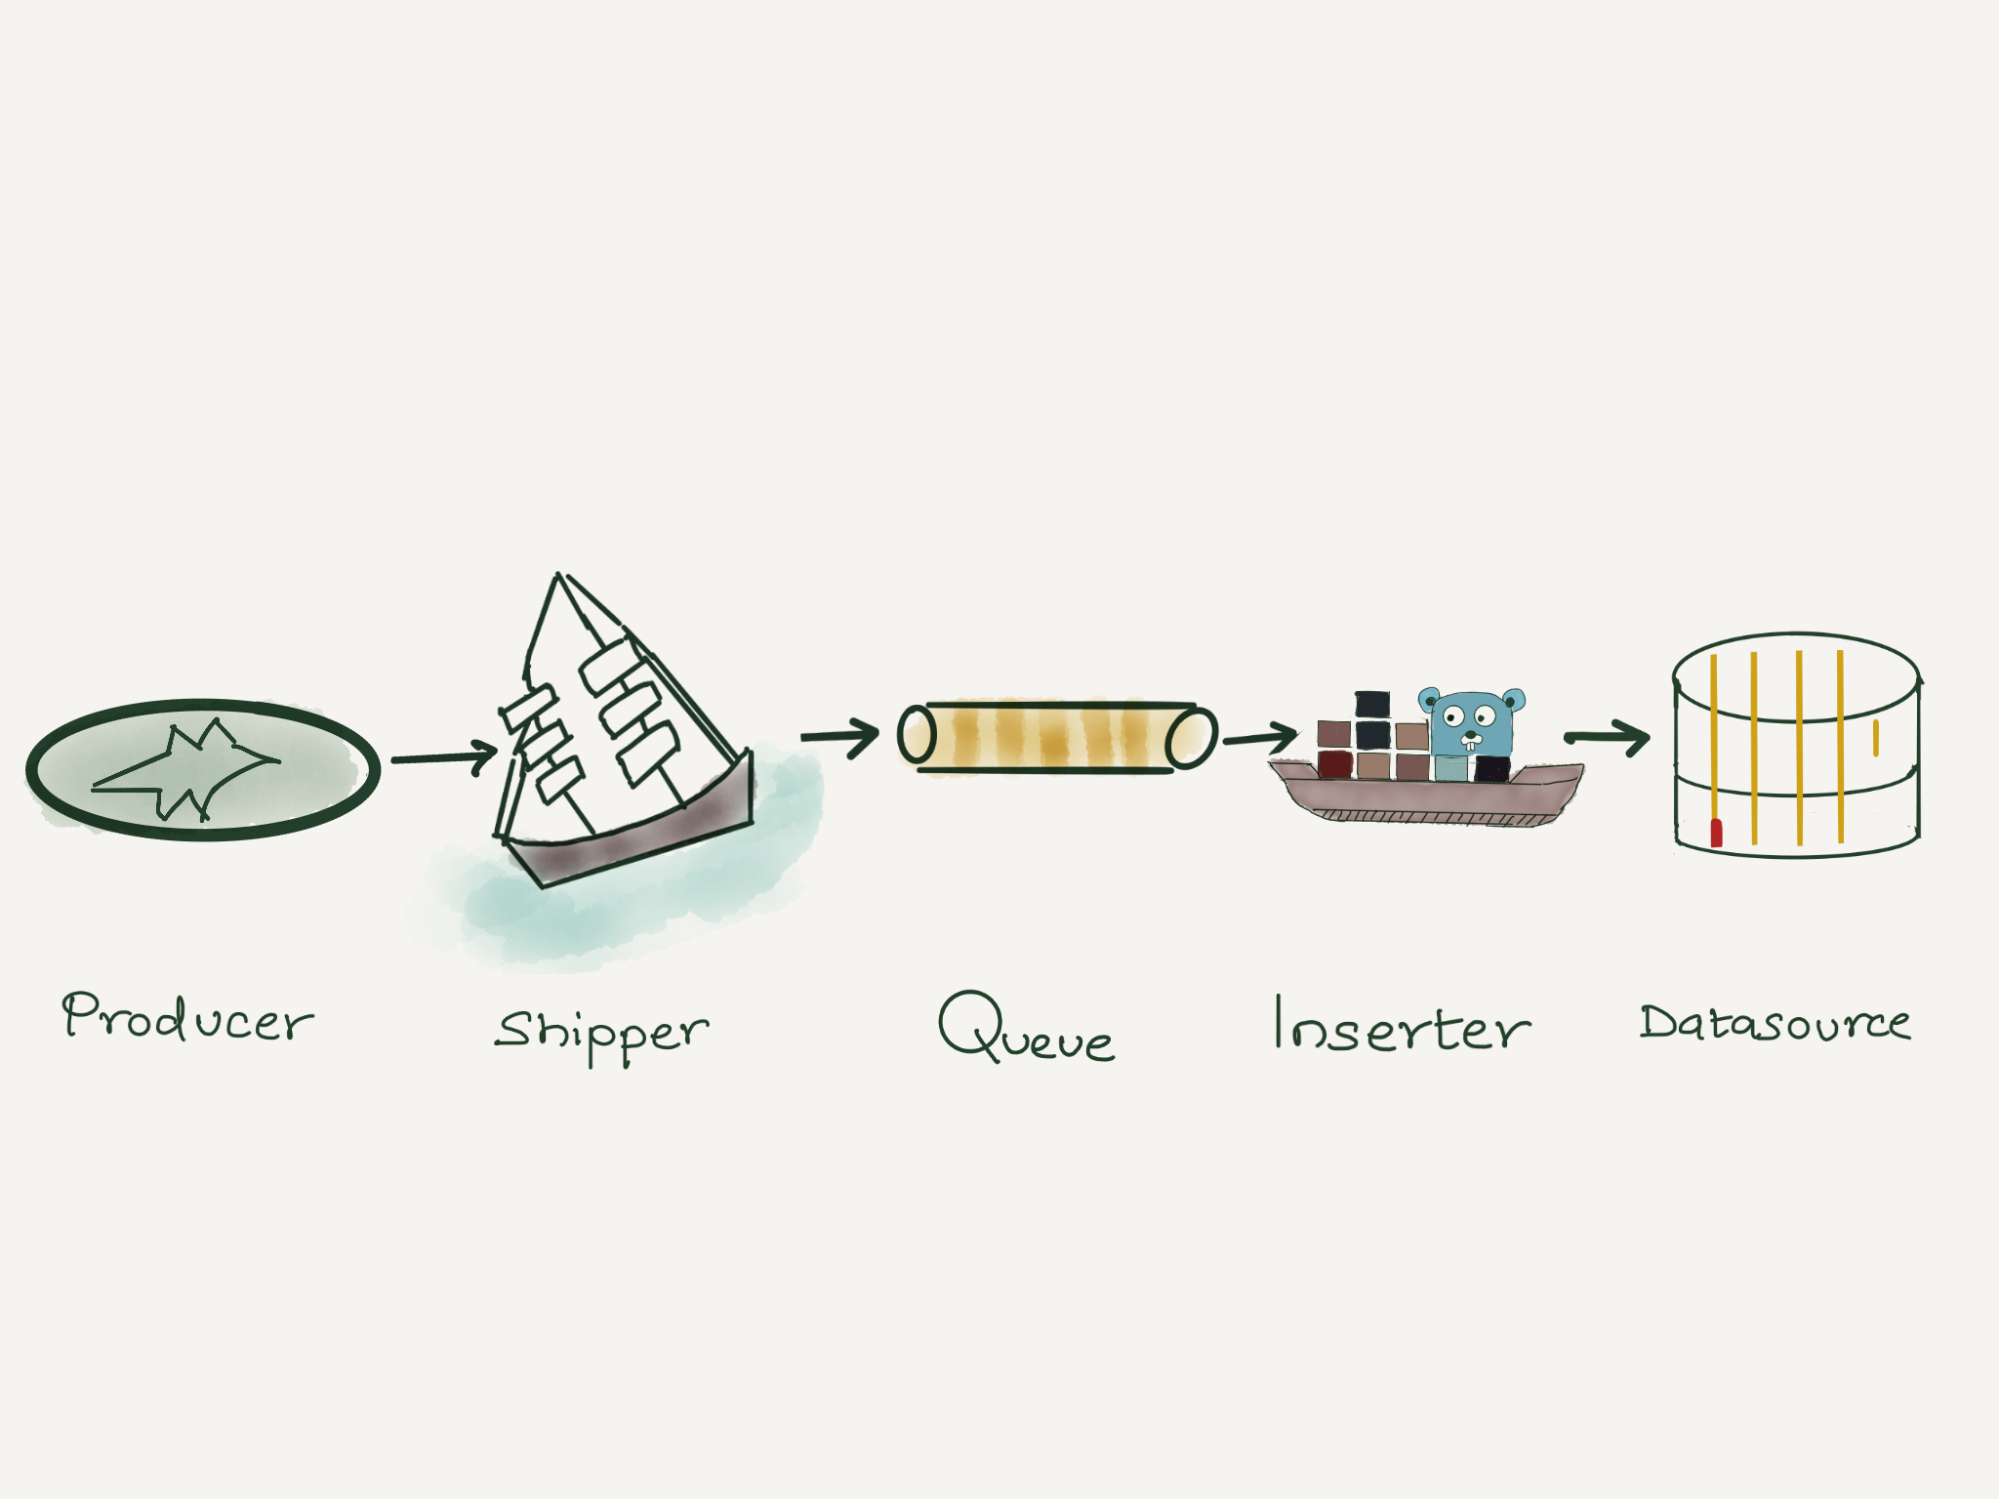
Like most other companies, our logging pipeline consists of a producer, shipper, a queue, a consumer and a datastore.
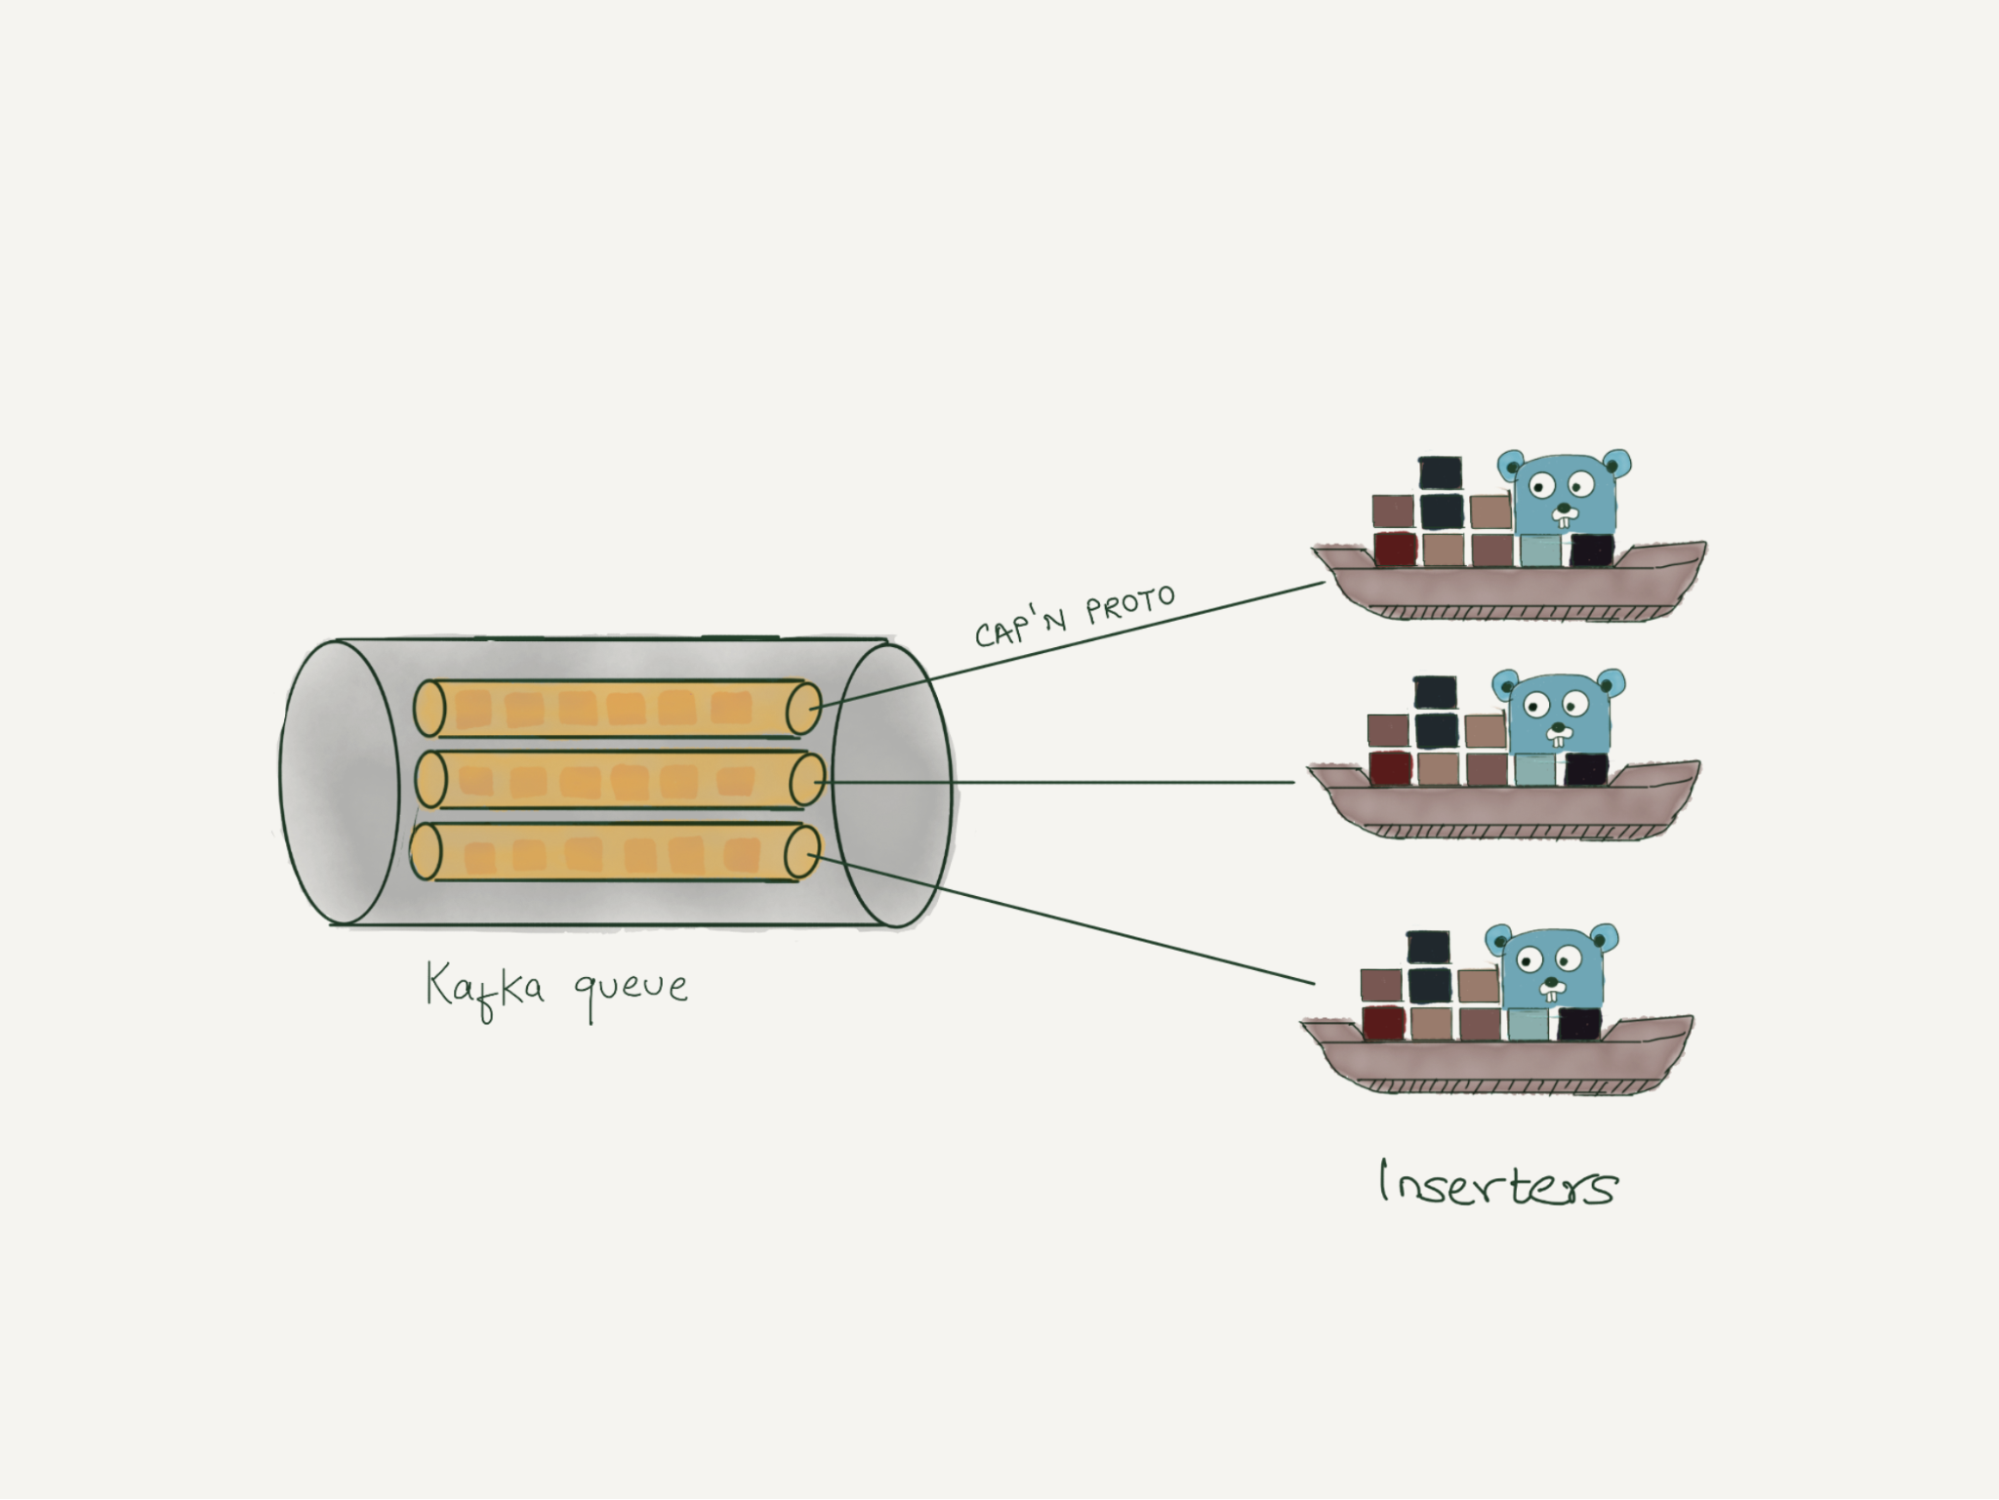
Applications (Producers) running on the Cloudflare global network generate the logs. These logs are written locally in Cap’n Proto serialized format. The Shipper (in-house solution) pushes the Cap’n Proto serialized logs through streams for processing to Kafka (queue). We run Logstash (consumer), which consumes from Kafka and writes the logs into ElasticSearch (datastore).The data is then visualized by using Kibana or Grafana. We have multiple dashboards built in both Kibana and Grafana to visualize the data.
Elasticsearch bottlenecks at Cloudflare
At Cloudflare, we have been running Elasticsearch clusters for many years. Over the years, log volume increased dramatically and while optimizing our Elasticsearch clusters to handle such volume, we found a few limitations.
Mapping Explosion
Mapping Explosion is one of the very well-known limitations of Elasticsearch. Elasticsearch maintains a mapping that decides how a new document and its fields are stored and indexed. When there are too many keys in this mapping, it can take a significant amount of memory resulting in frequent garbage collection. One way to prevent this is to make the schema strict, which means any log line not following this strict schema will end up getting dropped. Another way is to make it semi-strict, which means any field not part of this mapping will not be searchable.
Multi-tenancy support
Elasticsearch doesn’t have very good multi-tenancy support. One bad user can easily impact cluster performance. There is no way to limit the maximum number of documents or indexes a query can read or the amount of memory an Elasticsearch query can take. A bad query can easily degrade cluster performance and even after the query finishes, it can still leave its impact.
Cluster operational tasks
It is not easy to manage Elasticsearch clusters, especially multi-tenant ones. Once a cluster degrades, it takes significant time to get the cluster back to a fully healthy state. In Elasticsearch, updating the index template means reindexing the data, which is quite an overhead. We use hot and cold tiered storage, i.e., recent data in SSD and older data in magnetic drives. While Elasticsearch moves the data from hot to cold storage every day, it affects the read and write performance of the cluster.
Garbage collection
Elasticsearch is developed in Java and runs on a Java Virtual Machine (JVM). It performs garbage collection to reclaim memory that was allocated by the program but is no longer referenced. Elasticsearch requires garbage collection tuning. The default garbage collection in the latest JVM is G1GC. We tried other GC like ZGC, which helped in lowering the GC pause but didn’t give us much performance benefit in terms of read and write throughput.
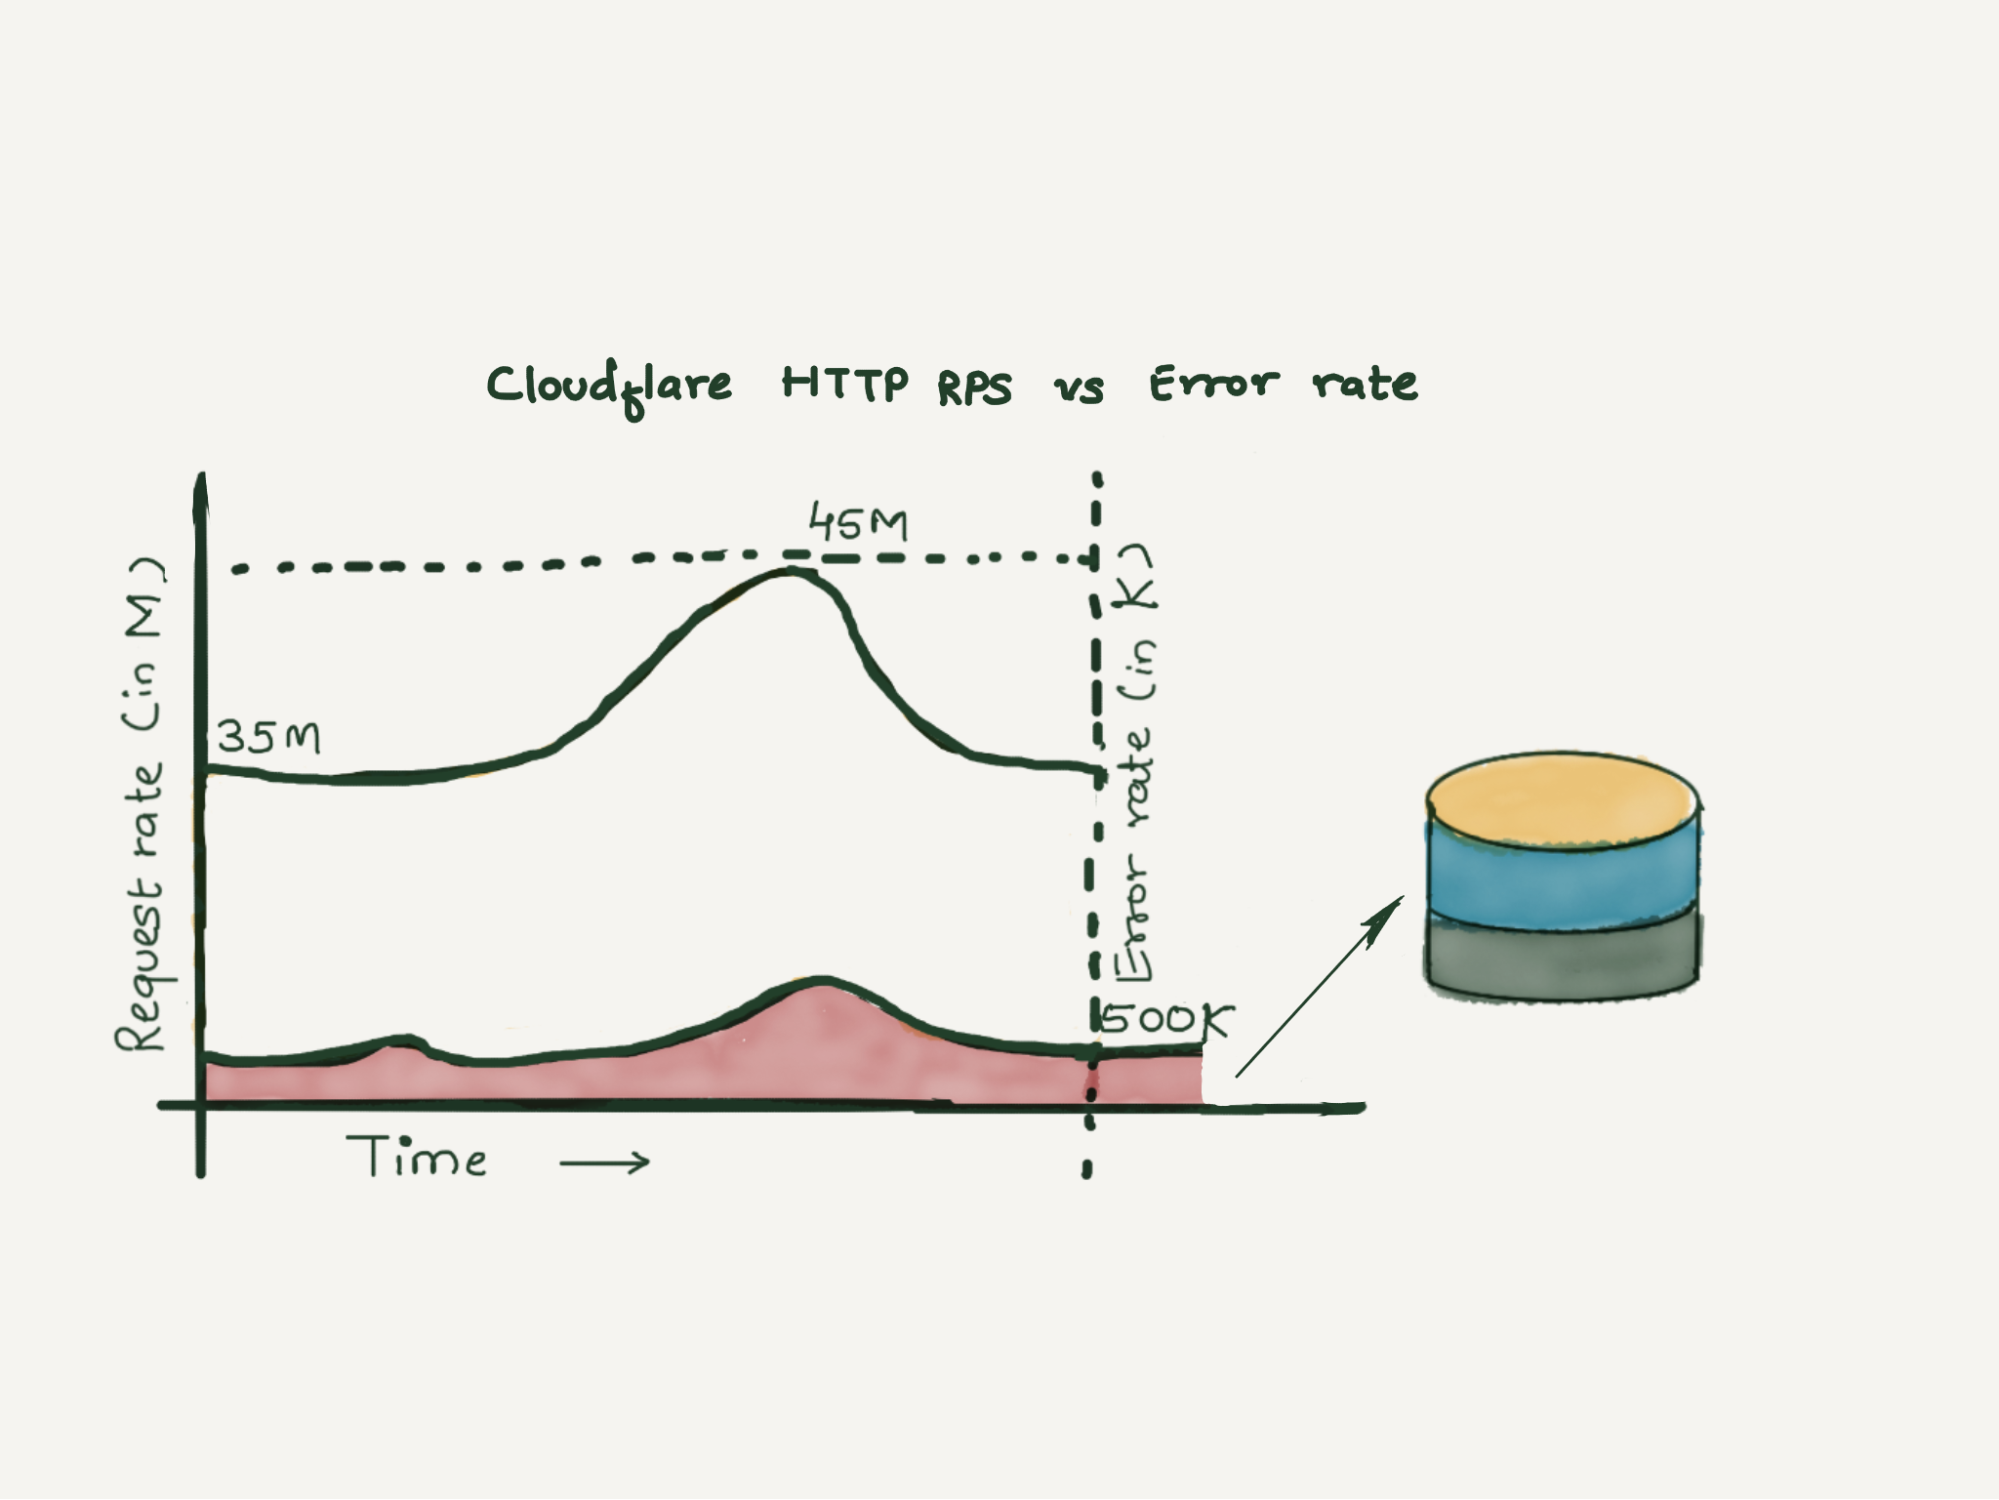
Elasticsearch is a good tool for full-text search and these limitations are not significant with small clusters, but in Cloudflare, we handle over 35 to 45 million HTTP requests per second, out of which over 500K-800K requests fail per second. These failures can be due to an improper request, origin server errors, misconfigurations by users, network issues and various other reasons.
Our customer support team uses these error logs as the starting point to triage customer issues. The error logs have a number of fields metadata about various Cloudflare products that HTTP requests have been through. We were storing these error logs in Elasticsearch. We were heavily sampling them since storing everything was taking a few hundreds of terabytes crossing our resource allocation budget. Also, dashboards built over it were quite slow since they required heavy aggregation over various fields. We need to retain these logs for a few weeks per the debugging requirements.
Proposed solution
We wanted to remove sampling completely, that is, store every log line for the retention period, to provide fast query support over this huge amount of data and to achieve all this without increasing the cost.
To solve all these problems, we decided to do a proof of concept and see if we could accomplish our requirements using ClickHouse.
Cloudflare was an early adopter of ClickHouse and we have been managing ClickHouse clusters for years. We already had a lot of in-house tooling and libraries for inserting data into ClickHouse, which made it easy for us to do the proof of concept. Let us look at some of the ClickHouse features that make it the perfect fit for storing logs and which enabled us to build our new logging pipeline.
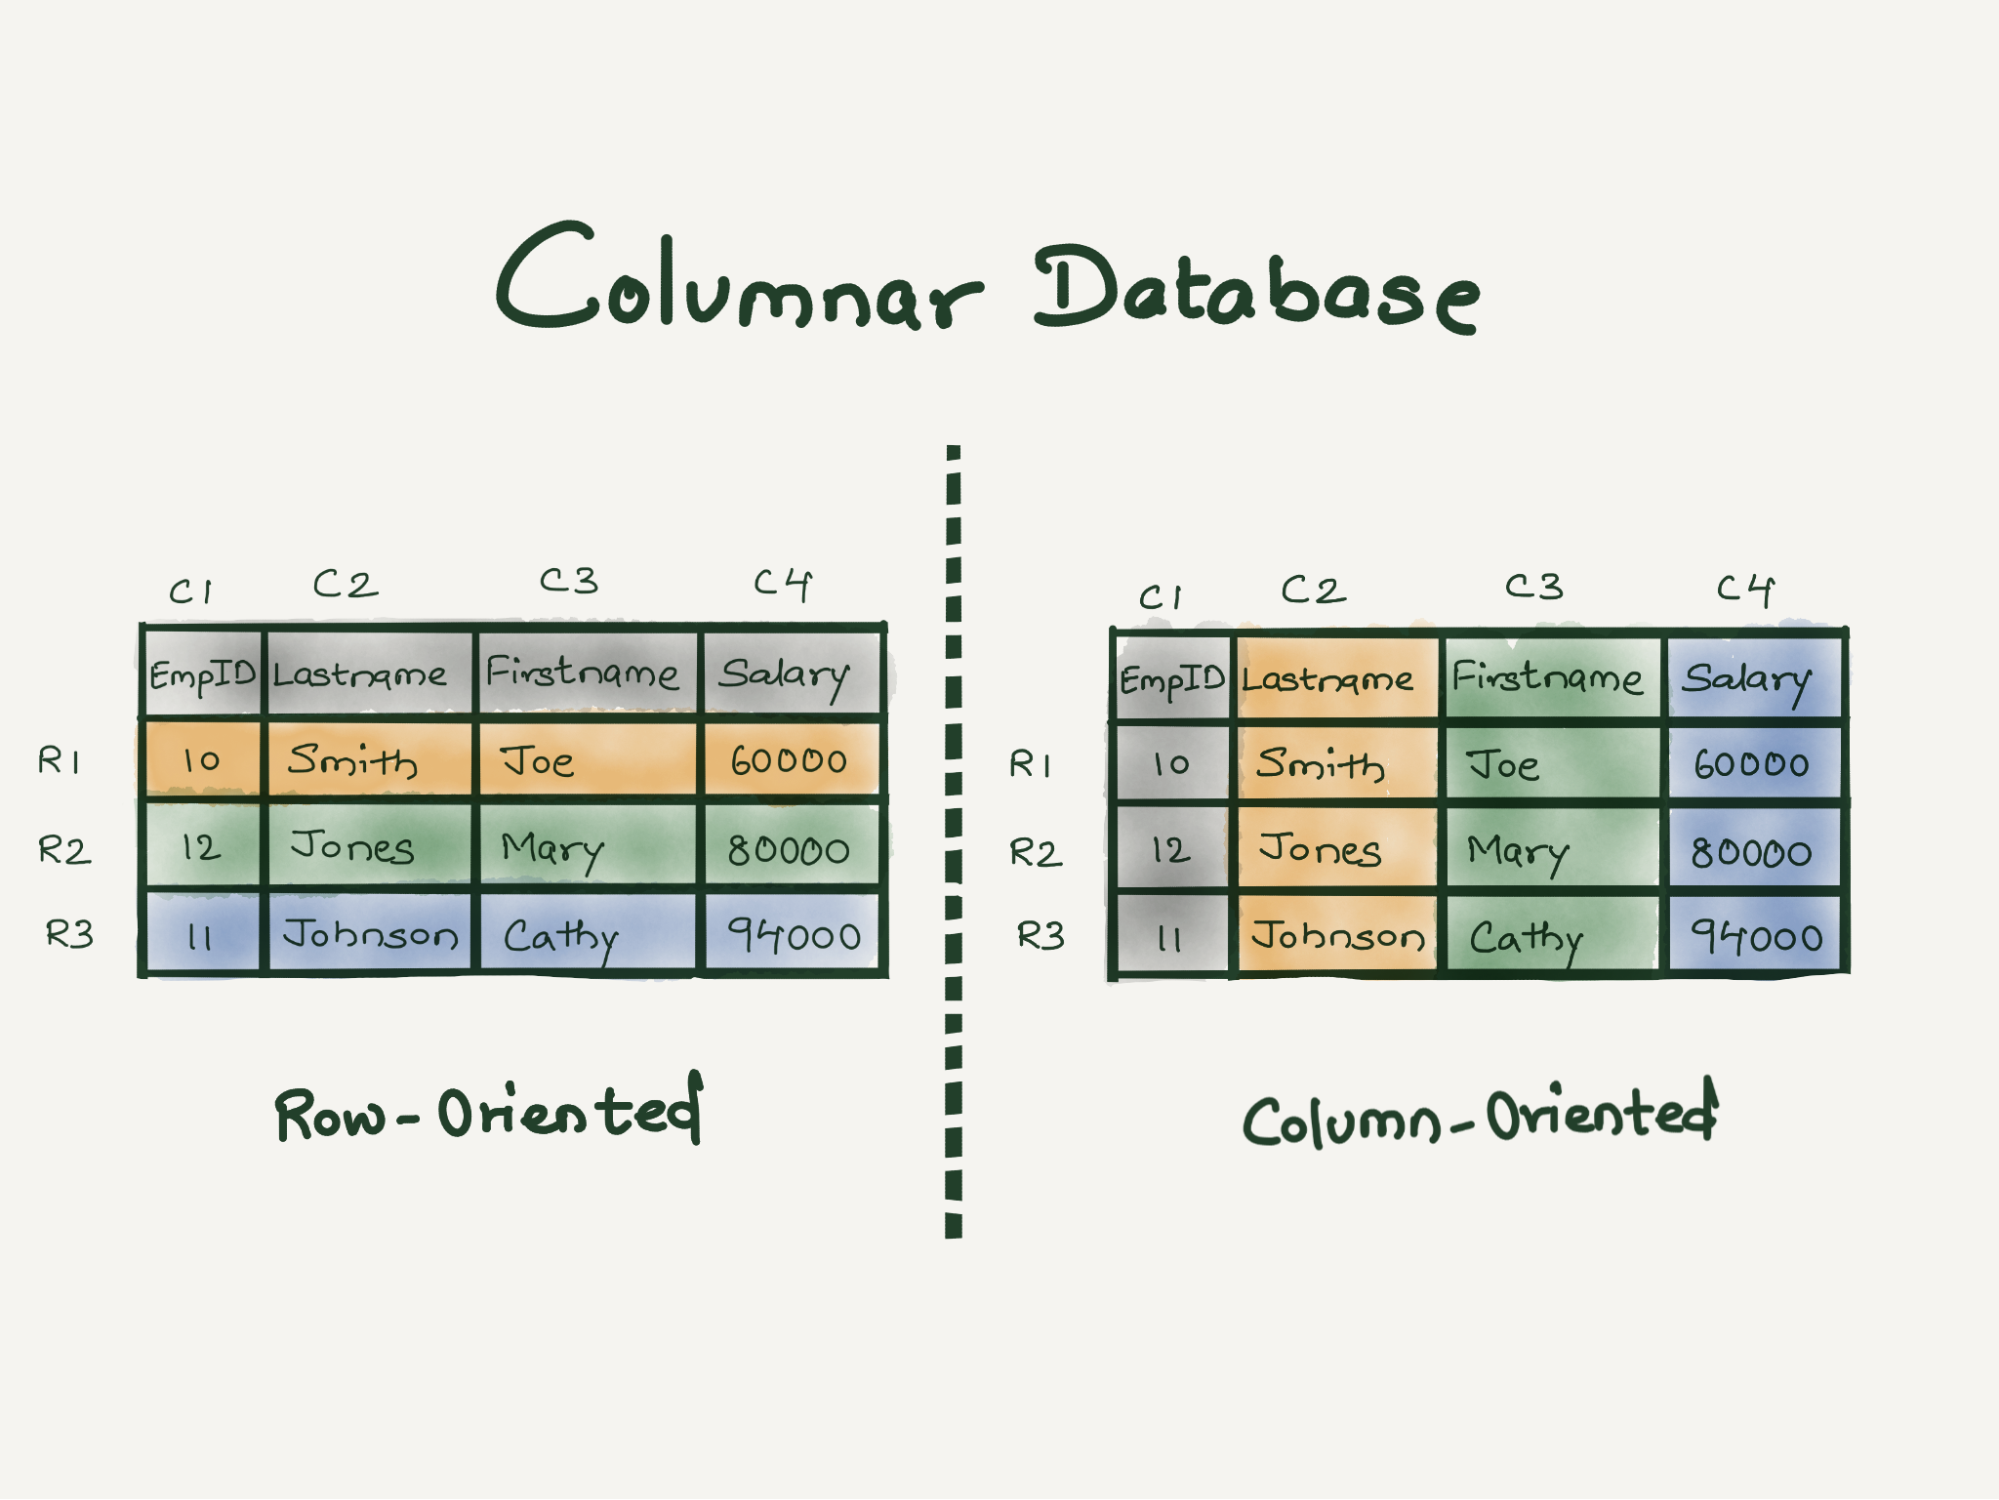
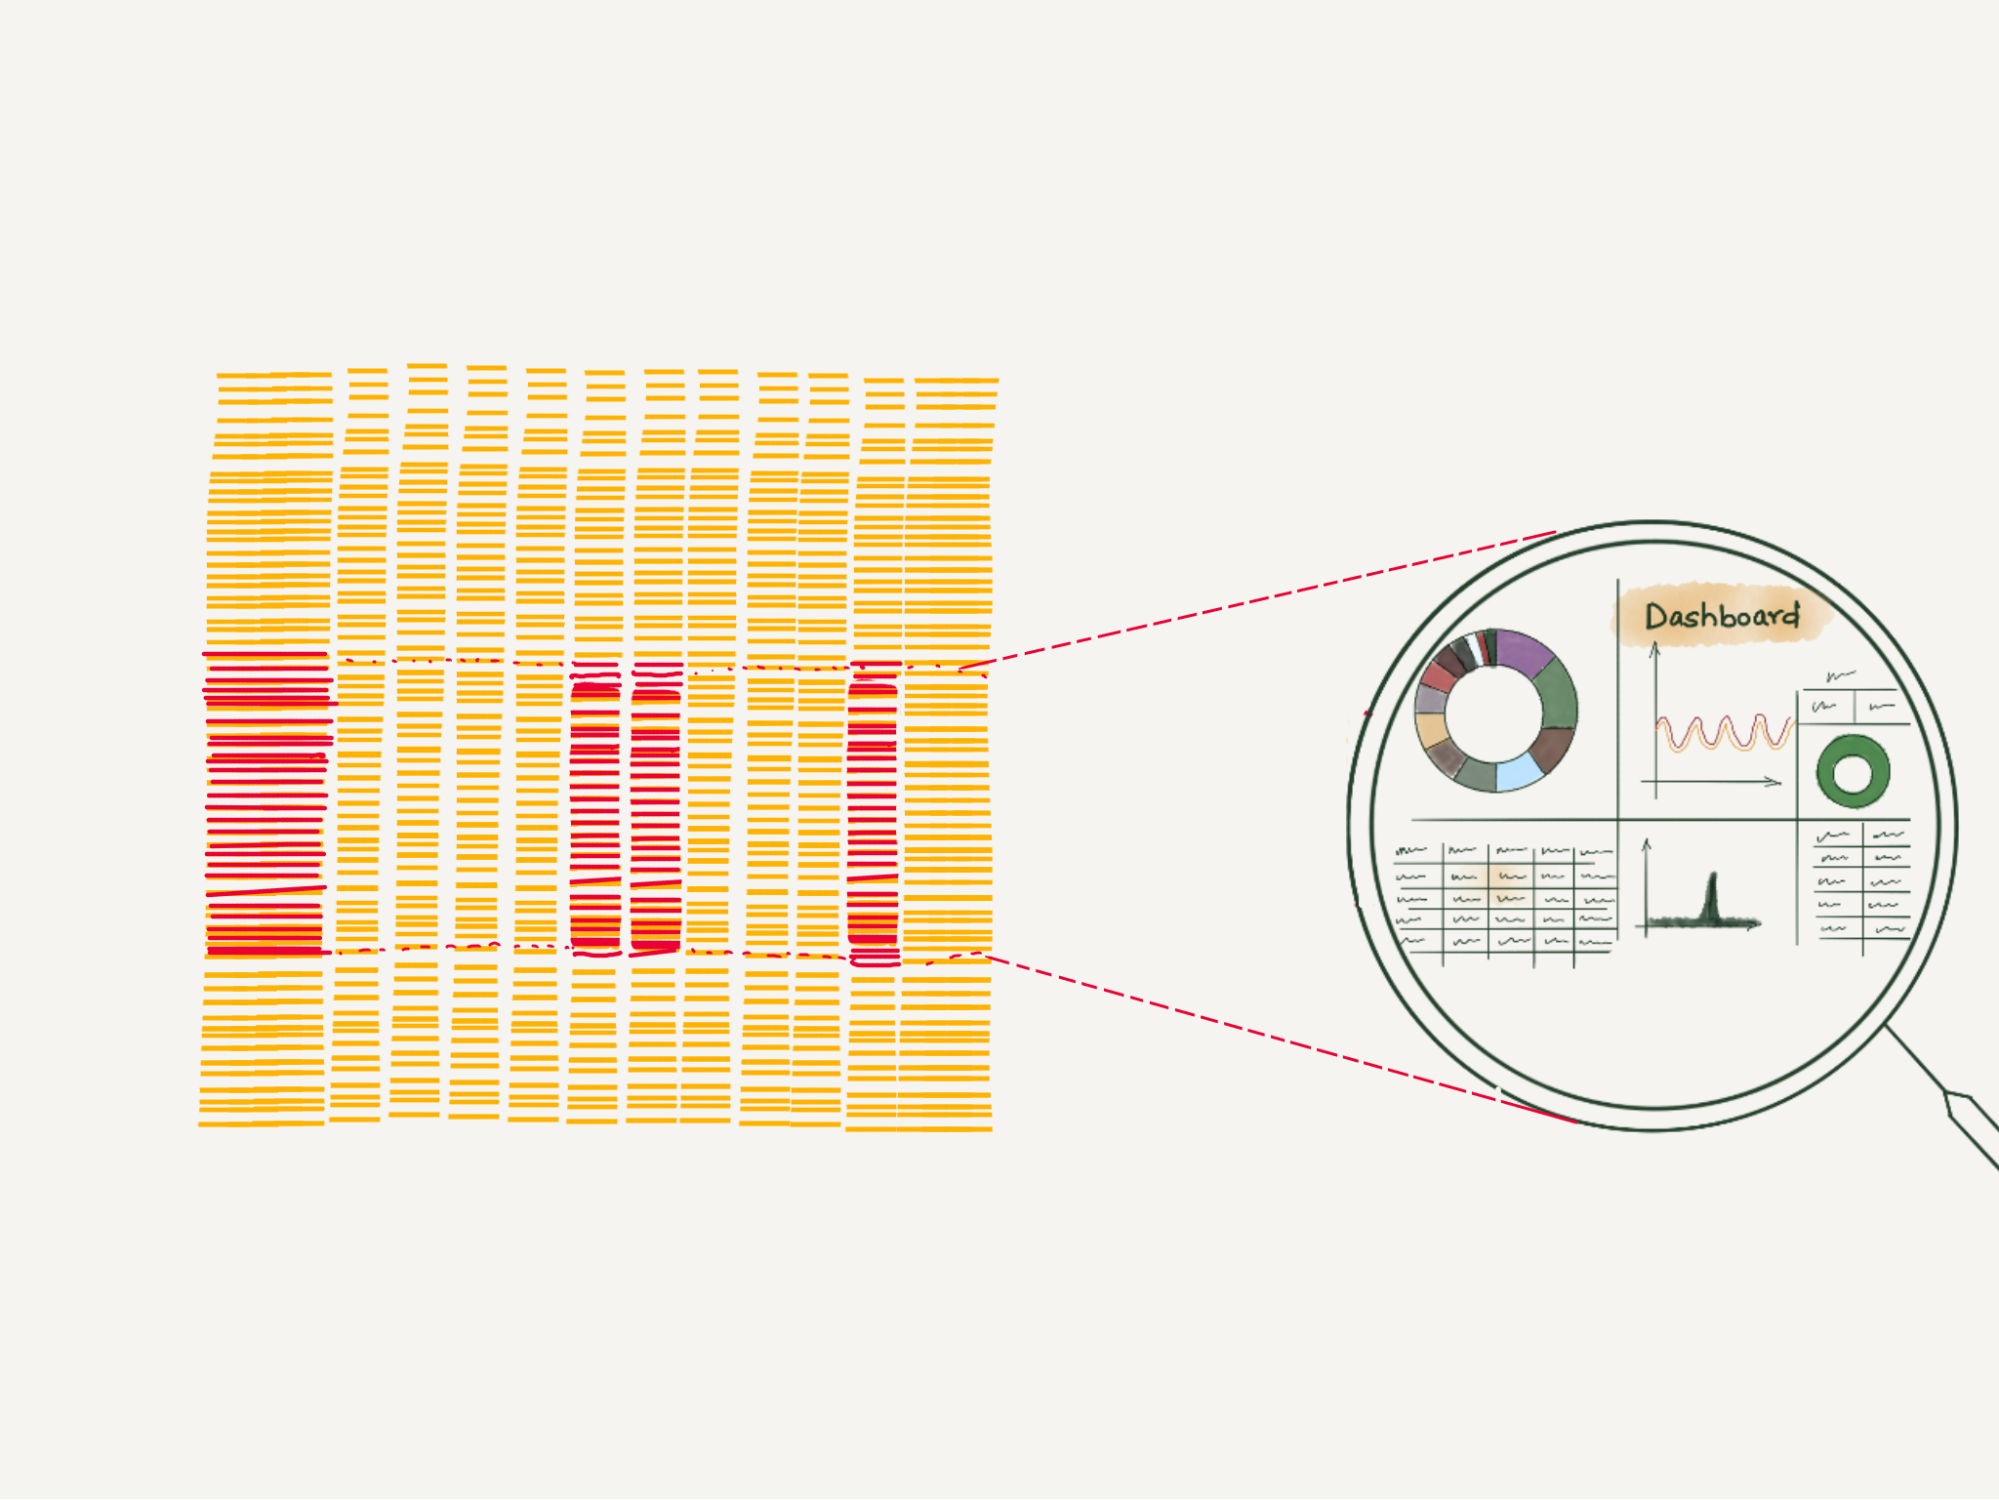
ClickHouse is a column-oriented database which means all data related to a particular column is physically stored next to each other. Such data layout helps in fast sequential scan even on commodity hardware. This enabled us to extract maximum performance out of older generation hardware.
ClickHouse is designed for analytical workloads where the data has a large number of fields that get represented as ClickHouse columns. We were able to design our new ClickHouse tables with a large number of columns without sacrificing performance.
ClickHouse indexes work differently than those in relational databases. In relational databases, the primary indexes are dense and contain one entry per table row. So if you have 1 million rows in the table, the primary index will also have 1 million entries. While In ClickHouse, indexes are sparse, which means there will be only one index entry per a few thousand table rows. ClickHouse indexes enabled us to add new indexes on the fly.
ClickHouse compresses everything with LZ4 by default. An efficient compression not only helps in minimizing the storage needs but also lets ClickHouse use page cache efficiently.
One of the cool features of ClickHouse is that the compression codecs can be configured on a per-column basis. We decided to keep default LZ4 compression for all columns. We used special encodings like Double-Delta for the DateTime columns, Gorilla for Float columns and LowCardinality for fixed-size String columns.
ClickHouse is linearly scalable; that is, the writes can be scaled by adding new shards and the reads can be scaled by adding new replicas. Every node in a ClickHouse cluster is identical. Not having any special nodes helps in scaling the cluster easily.
Let’s look at some optimizations we leveraged to provide faster read/write throughput and better compression on log data.
Inserter
Having an efficient inserter is as important as having an efficient data store. At Cloudflare, we have been operating quite a few analytics pipelines from where we borrowed most of the concepts while writing our new inserter. We use Cap’n Proto messages as the transport data format since it provides fast data encoding and decoding. Scaling inserters is easy and can be done by adding more Kafka partitions and spawning new inserter pods.
Batch Size
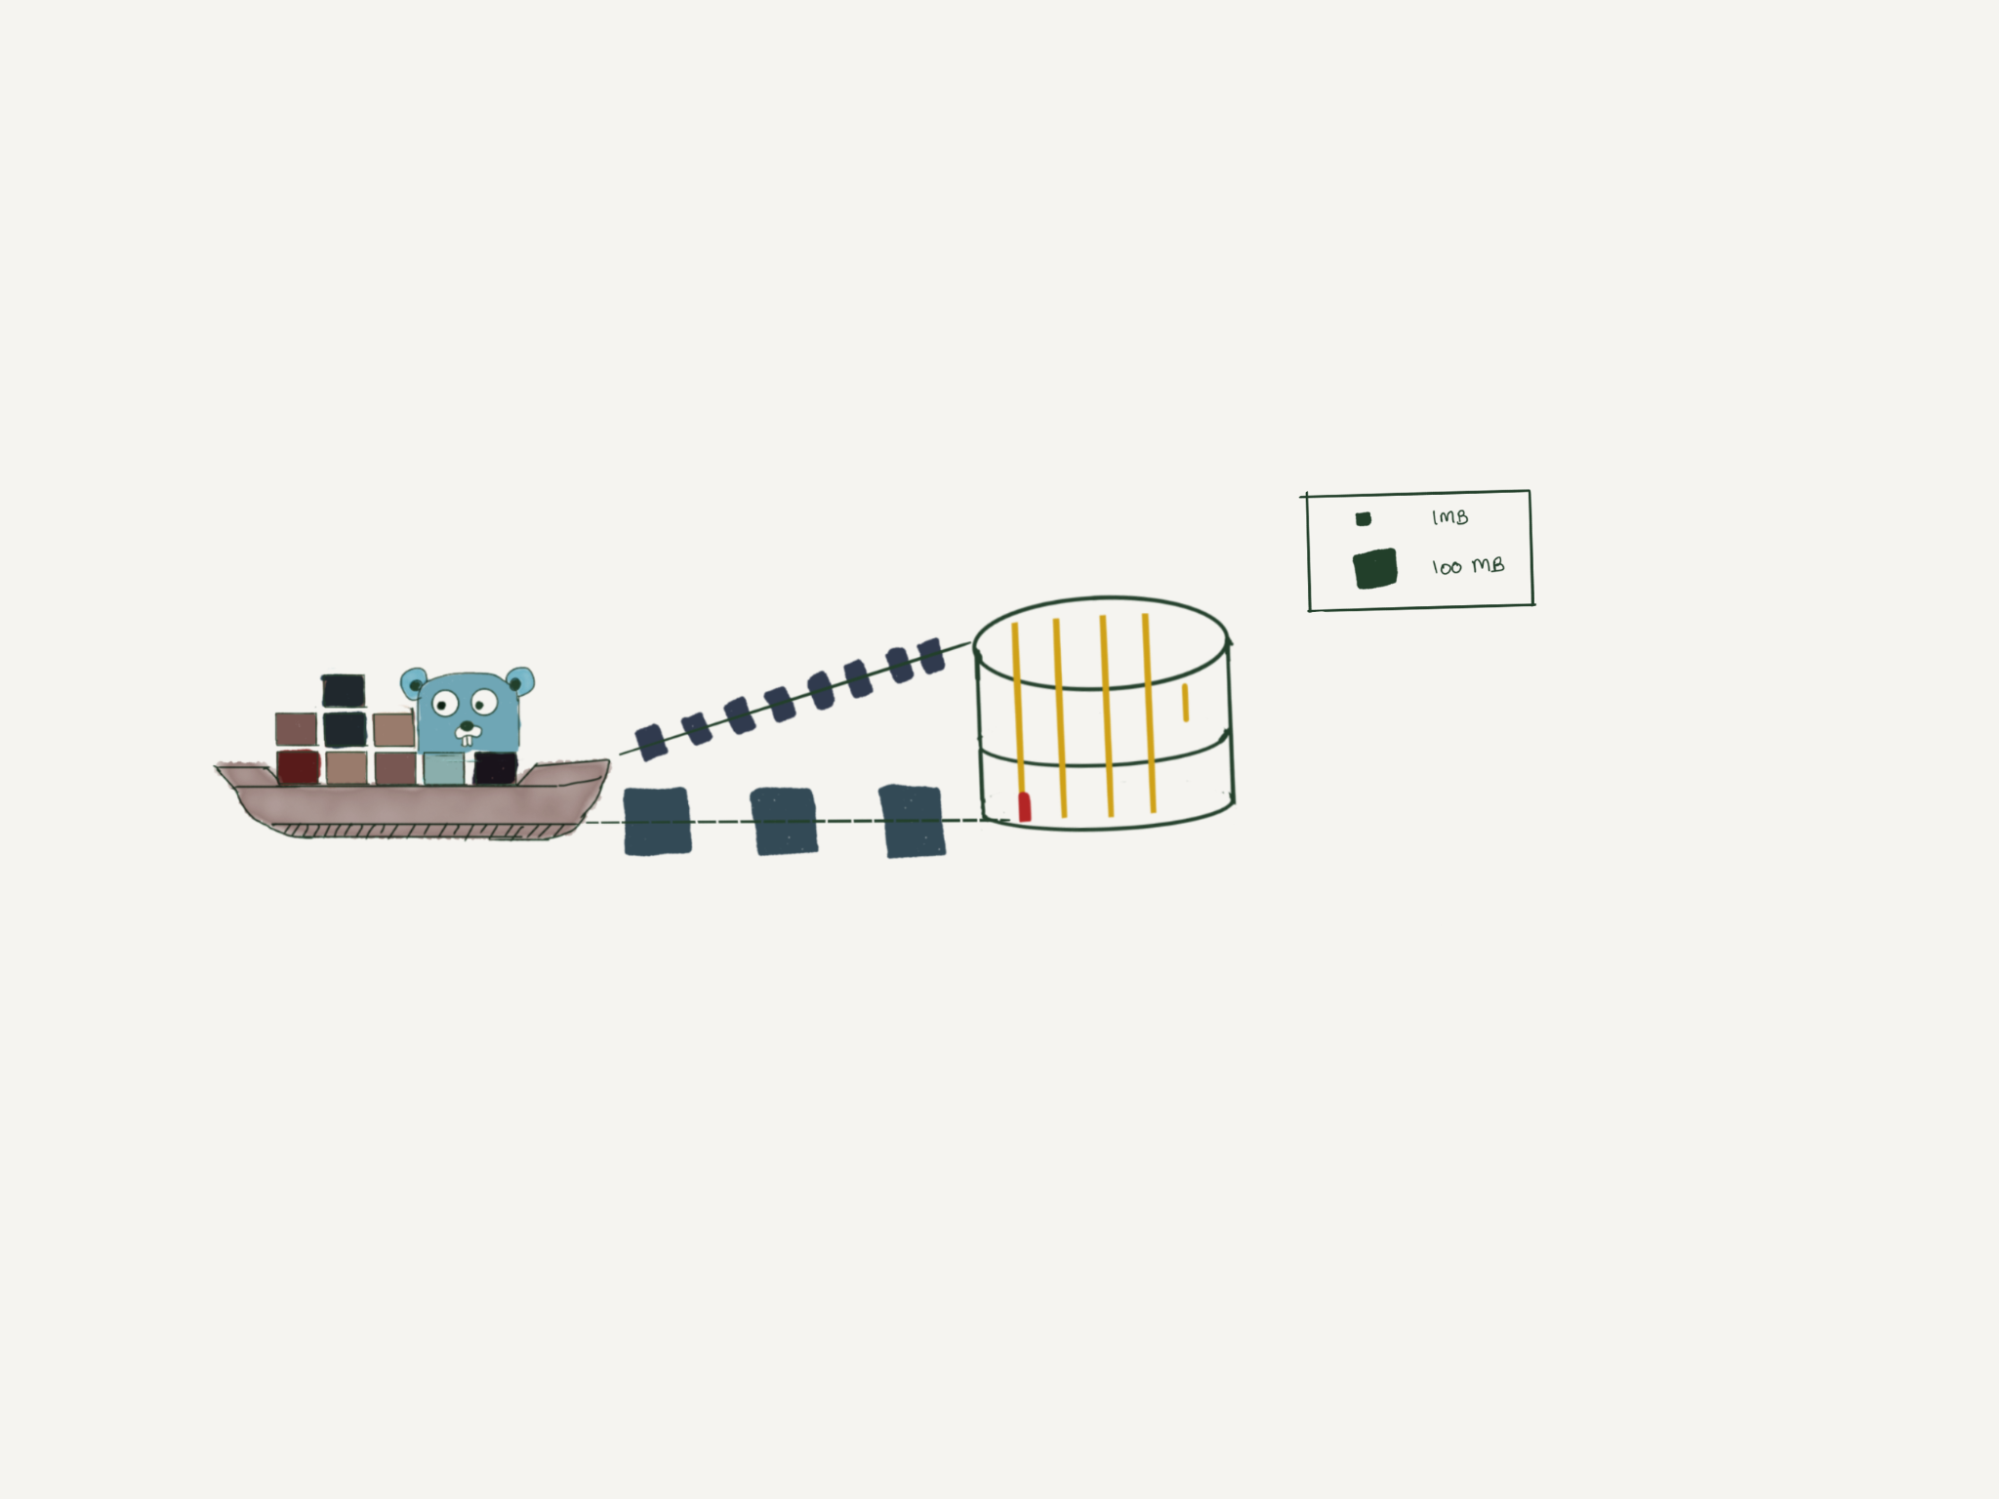
One of the key performance factors while inserting data into ClickHouse is the batch size. When batches are small, ClickHouse creates many small partitions, which it then merges into bigger ones. Thus smaller batch size creates extra work for ClickHouse to do in the background, thereby reducing ClickHouse’s performance. Hence it is crucial to set it big enough that ClickHouse can accept the data batch happily without hitting memory limits.
Data modeling in ClickHouse.
ClickHouse provides in-built sharding and replication without any external dependency. Earlier versions of ClickHouse depended on ZooKeeper for storing replication information, but the recent version removed the ZooKeeper dependency by adding clickhouse-keeper.
To read data across multiple shards, we use distributed tables, a special kind of table. These tables don’t store any data themselves but act as a proxy over multiple underlying tables storing the actual data.
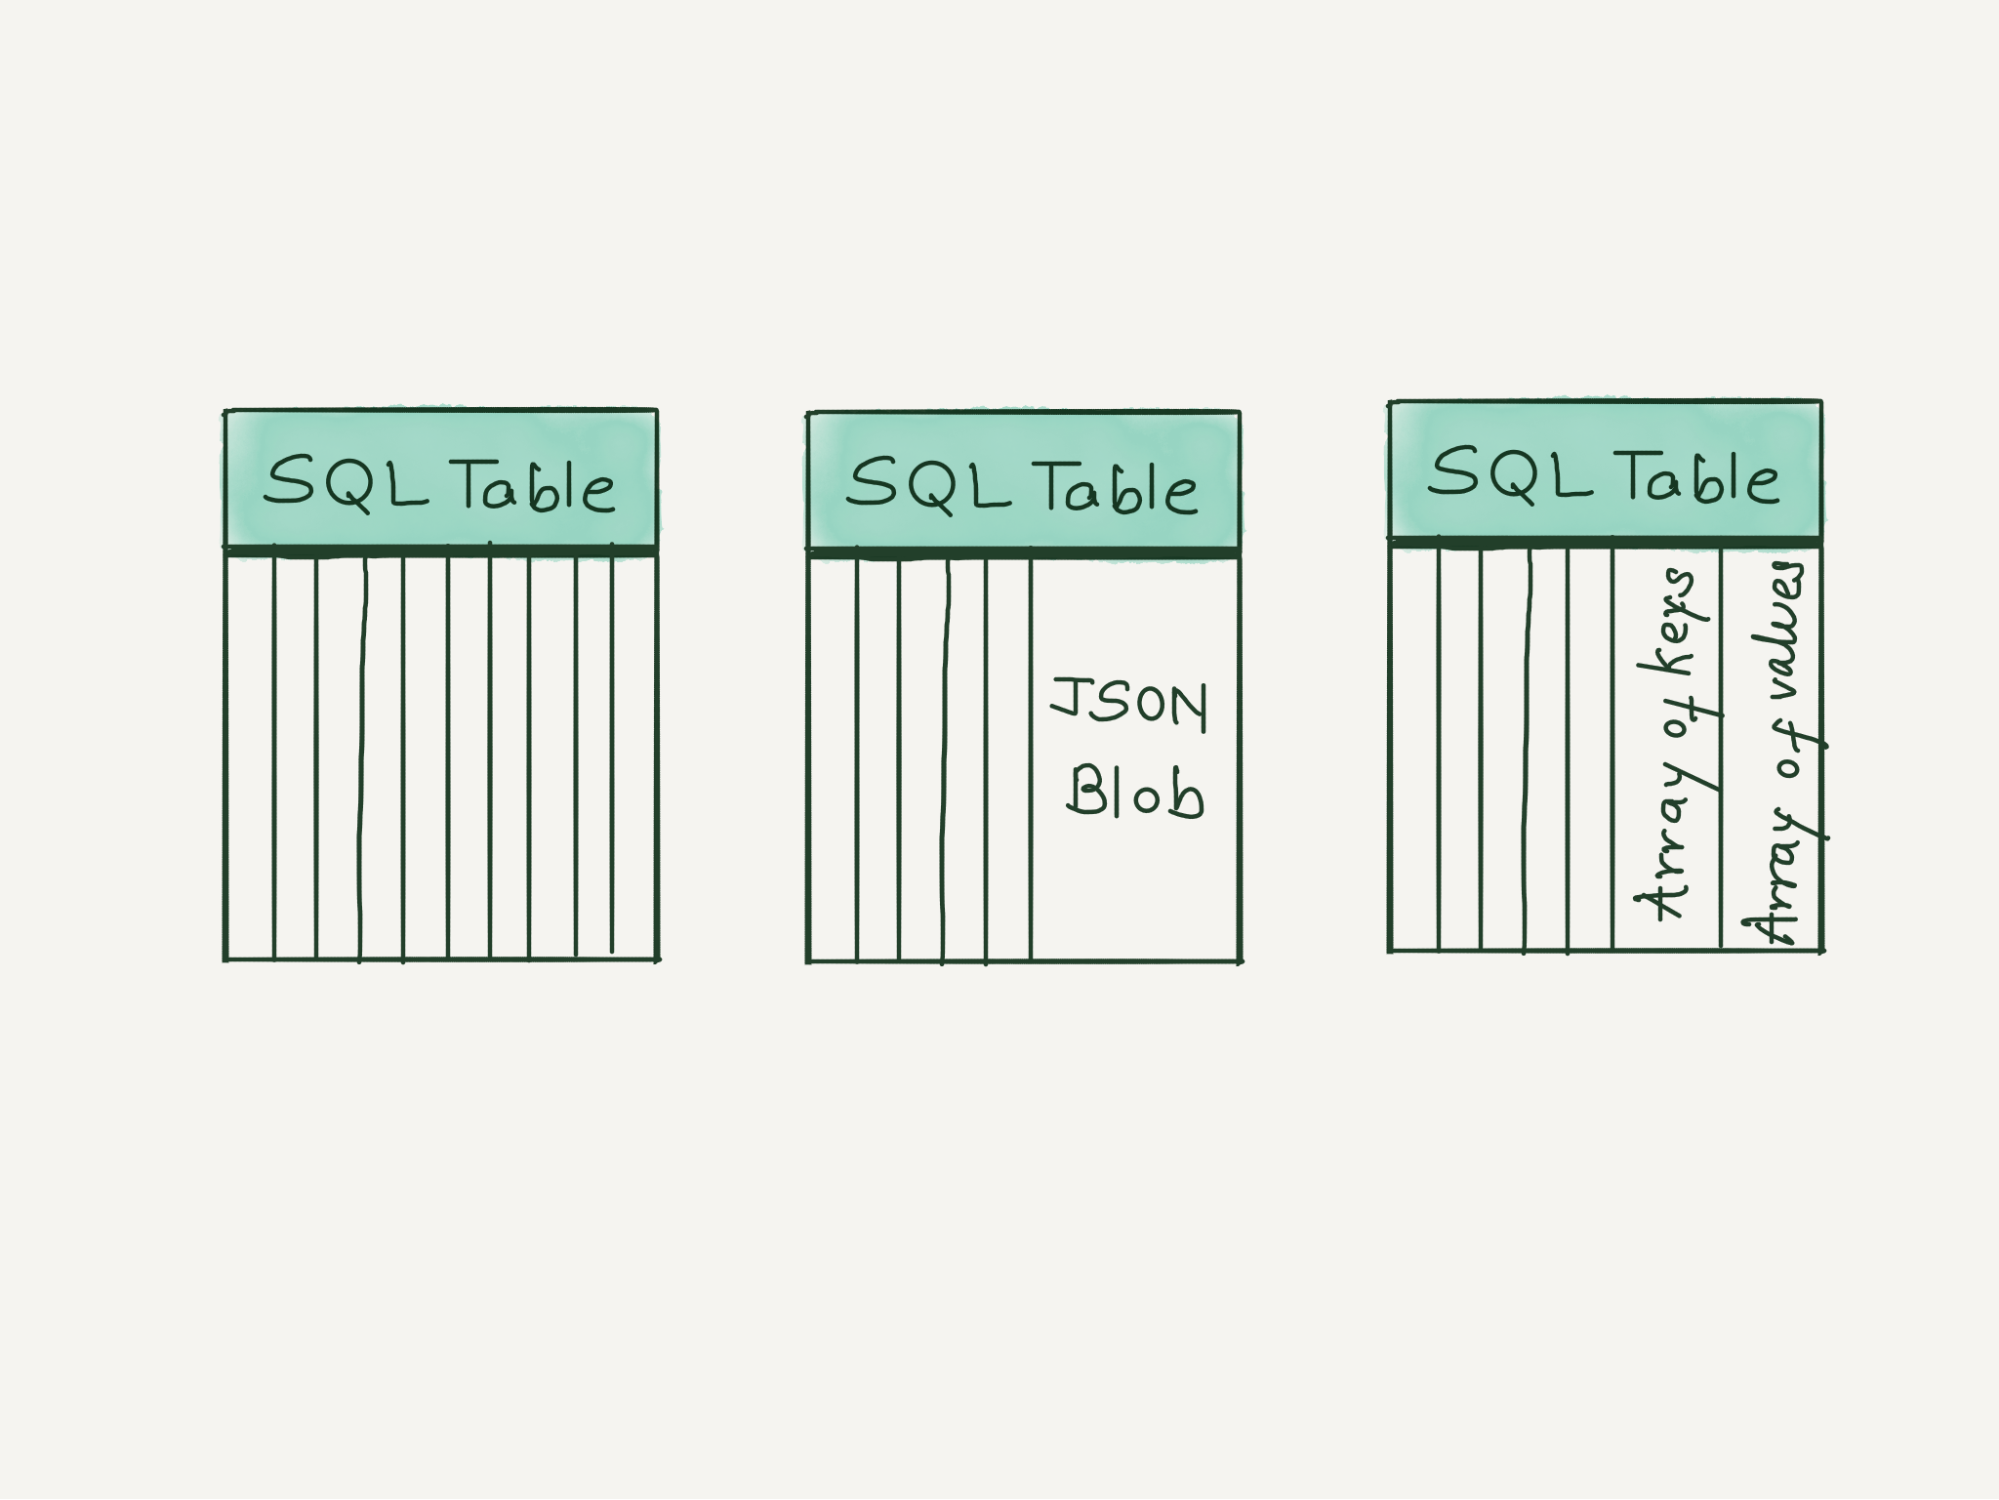
Like any other database, choosing the right table schema is very important since it will directly impact the performance and storage utilization. We would like to discuss three ways you can store log data into ClickHouse.
The first is the simplest and the most strict table schema where you specify every column name and data type. Any logline having a field outside this predefined schema will get dropped. From our experience, this schema will give you the fastest query capabilities. If you already know the list of all possible fields ahead, we would recommend using it. You can always add or remove columns by running ALTER TABLE queries.
The second schema uses a very new feature of ClickHouse, where it does most of the heavy lifting. You can insert logs as JSON objects and behind the scenes, ClickHouse will understand your log schema and dynamically add new columns with appropriate data type and compression. This schema should only be used if you have good control over the log schema and the number of total fields is less than 1,000. On the one hand it provides flexibility to add new columns as new log fields automatically, but at the same time, one lousy application can easily bring down the ClickHouse cluster.
The third schema stores all fields of the same data type in one array and then uses ClickHouse inbuilt array functions to query those fields. This schema scales pretty well even when there are more than 1,000 fields, as the number of columns depends on the data types used in the logs. If an array element is accessed frequently, it can be taken out as a dedicated column using the materialized column feature of ClickHouse. We recommend adopting this schema since it provides safeguards against applications logging too many fields.
Data partitioning
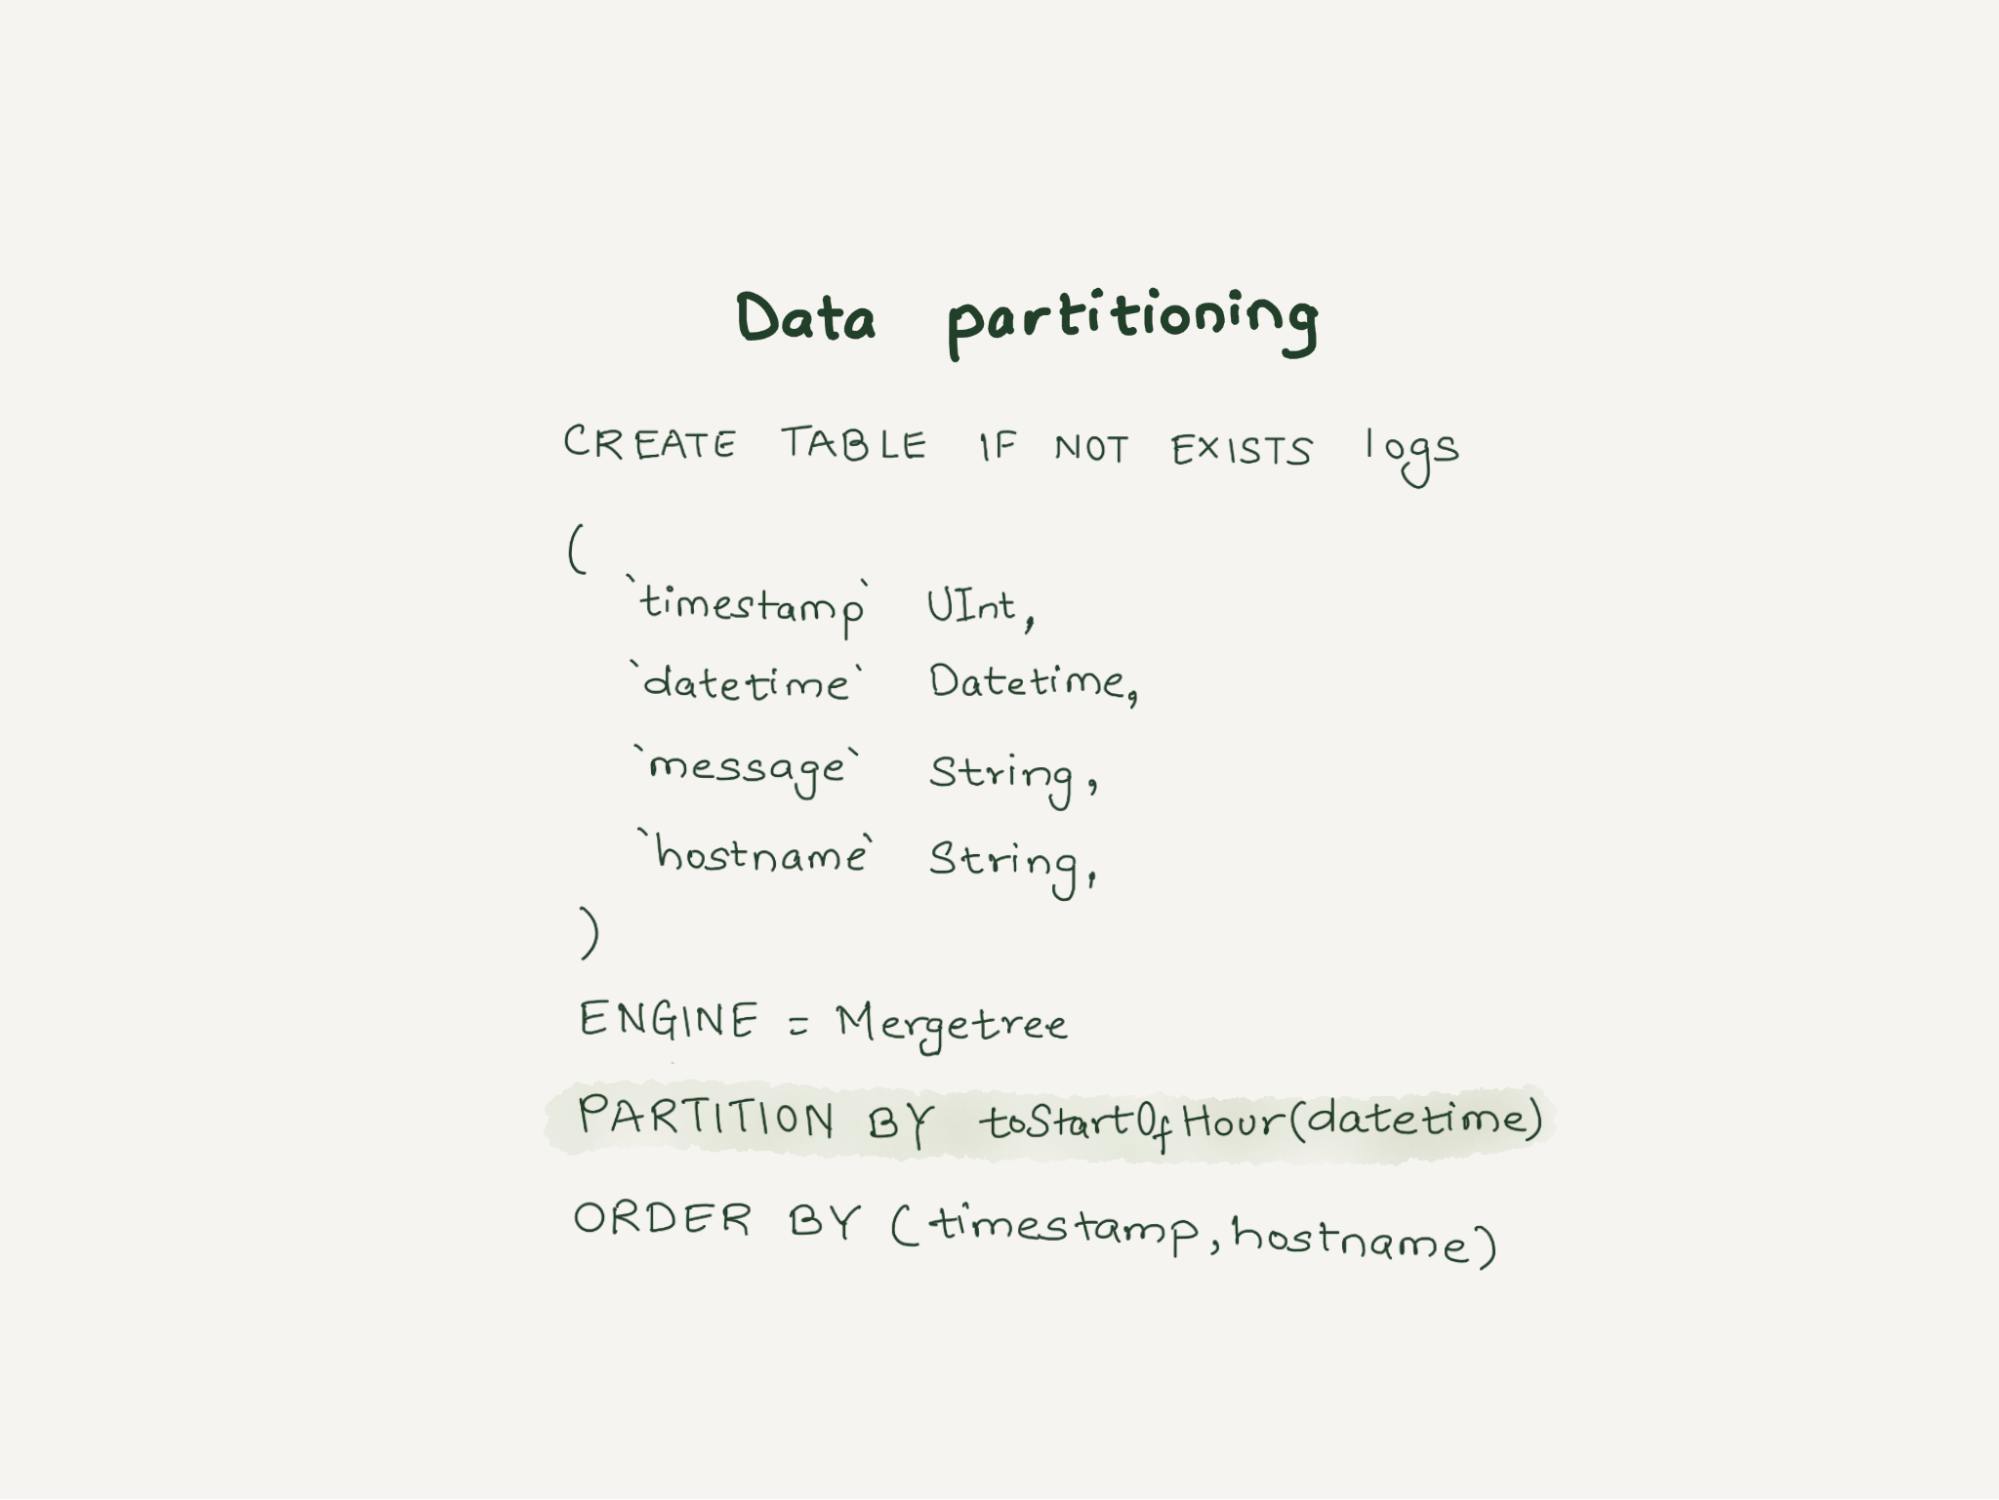
A partition is a unit of ClickHouse data. One common mistake ClickHouse users make is overly granular partitioning keys, resulting in too many partitions. Since our logging pipeline generates TBs of data daily, we created the table partitioned with `toStartOfHour(dateTime).` With this partitioning logic, when a query comes with the timestamp in the WHERE clause, ClickHouse knows the partition and retrieves it quickly. It also helps design efficient data purging rules according to the data retention policies.
Primary key selection
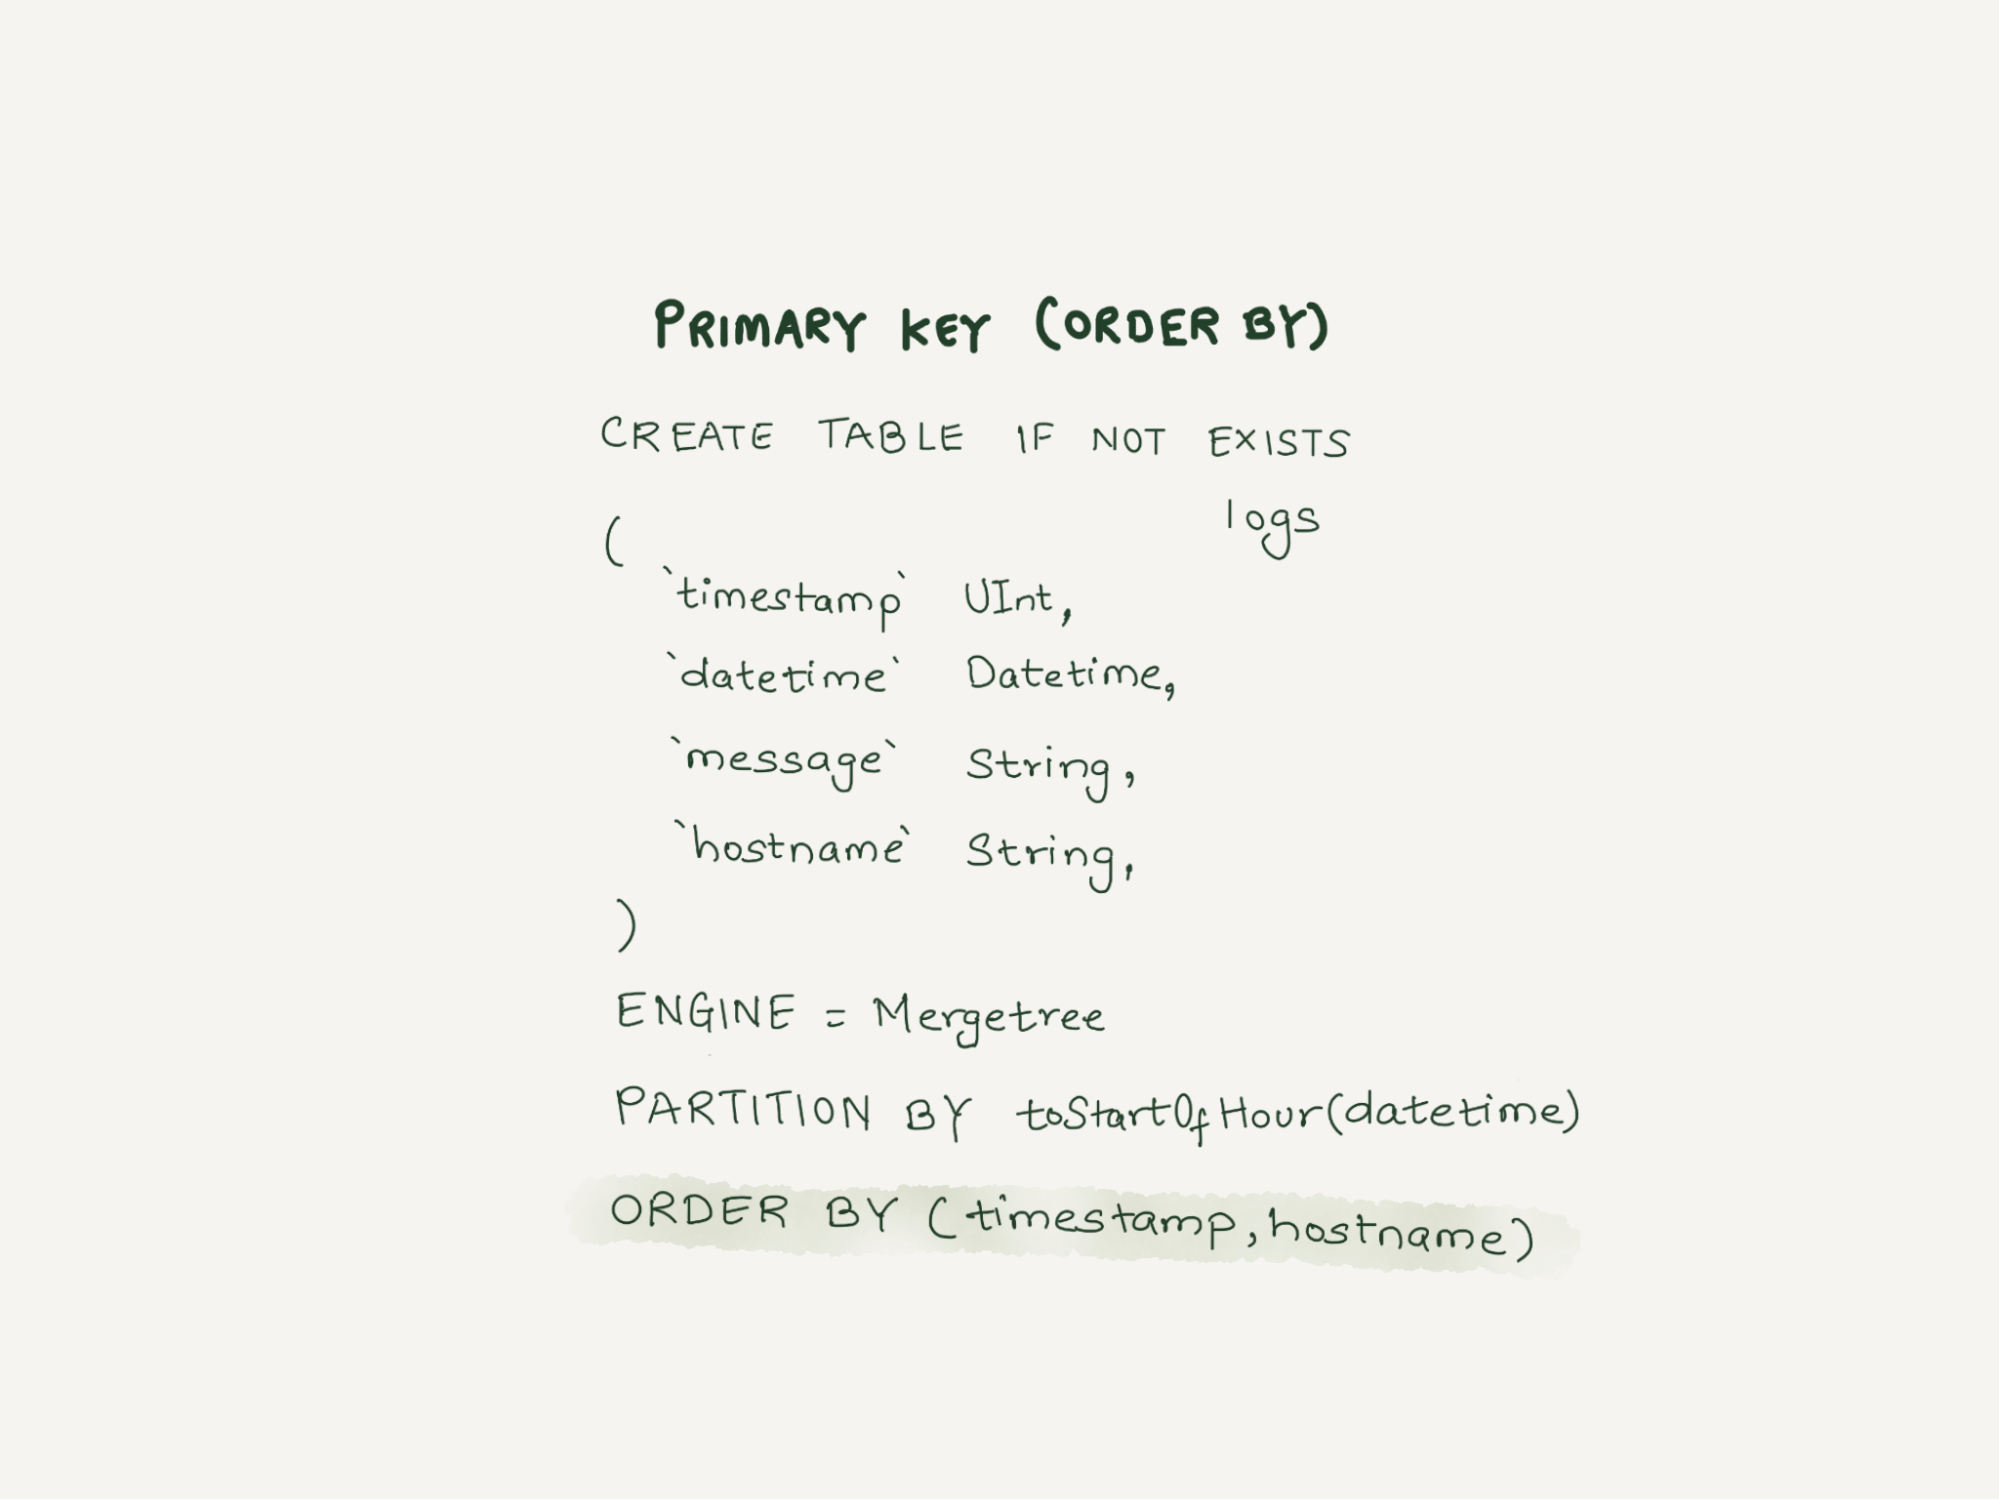
ClickHouse stores the data on disk sorted by primary key. Thus, selecting the primary key impacts the query performance and helps in better data compression. Unlike relational databases, ClickHouse doesn’t require a unique primary key per row and we can insert multiple rows with identical primary keys. Having multiple primary keys will negatively impact the insertion performance. One of the significant ClickHouse limitations is that once a table is created the primary key can not be updated.
Data skipping indexes
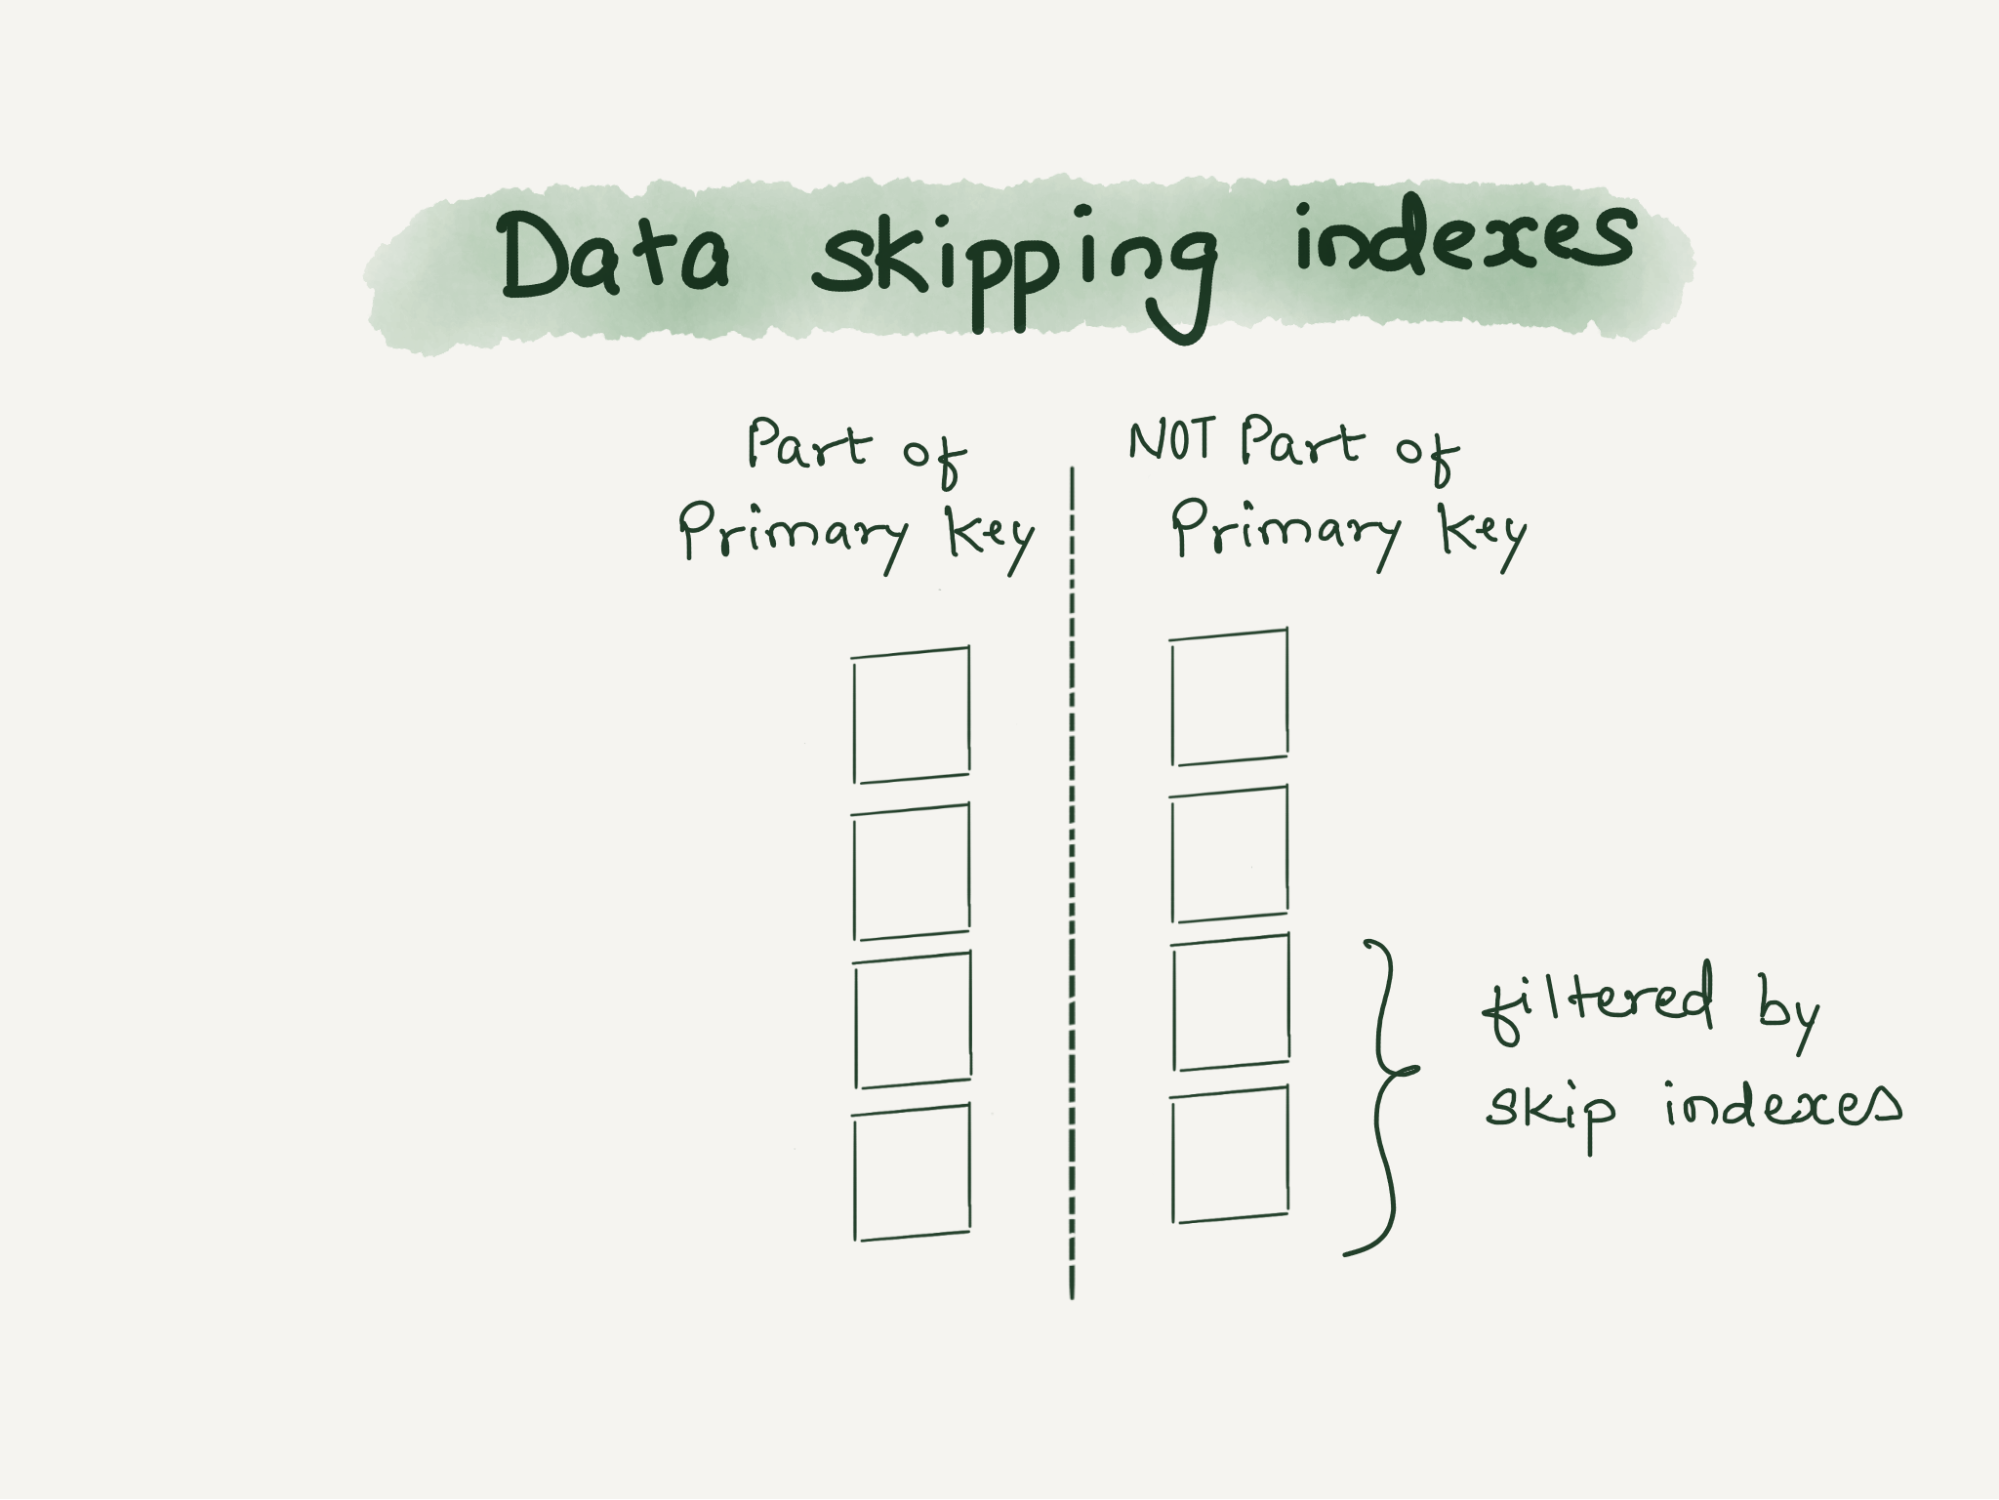
ClickHouse query performance is directly proportional to whether it can use the primary key when evaluating the WHERE clause. We have many columns and all these columns can not be part of the primary key. Thus queries on these columns will have to do a full scan resulting in slower queries. In traditional databases, secondary indexes can be added to handle such situations. In ClickHouse, we can add another class of indexes called data skipping indexes, which uses bloom filters and skip reading significant chunks of data that are guaranteed to have no match.
ABR
We have multiple dashboards built over the requests_error logs. Loading these dashboards were often hitting the memory limits set for the individual query/user in ClickHouse.
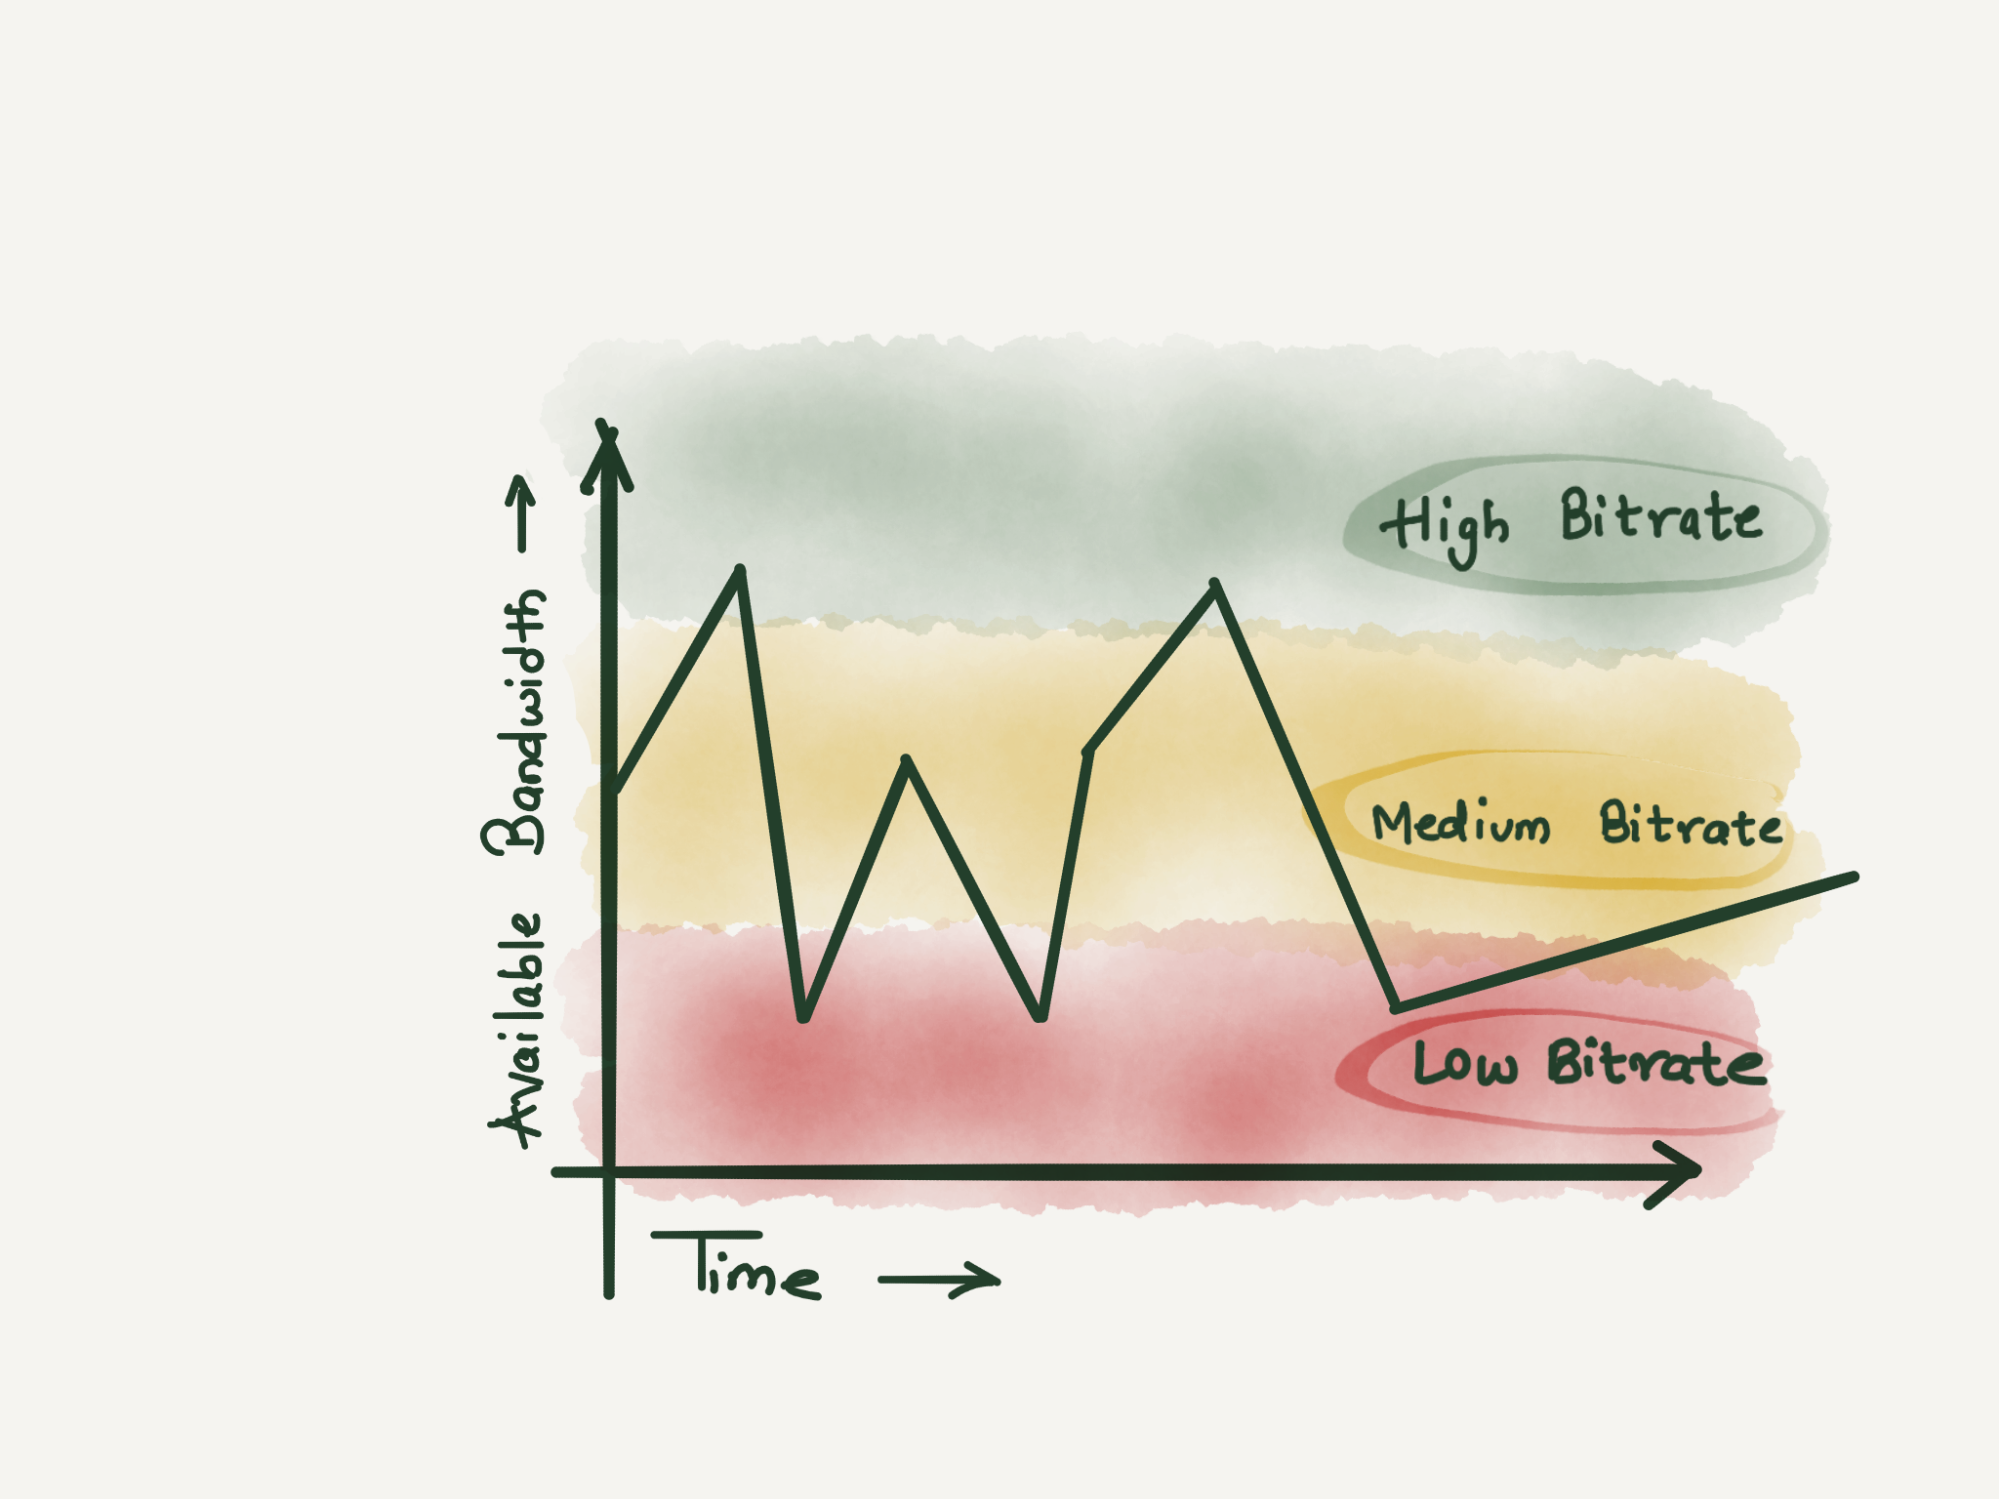
The dashboards built over these logs were mainly used to identify anomalies. To visually identify an anomaly in a metric, the exact numbers are not required, but an approximate number would do. For instance, to understand that errors have increased in a data center, we don’t need the exact number of errors. So we decided to use an in-house library and tool built around a concept called ABR.
ABR stands for “Adaptive Bit Rate” – the term ABR is mainly used in video streaming services where servers select the best resolution for a video stream to match the client and network connection. It is described in great detail in the blog post – Explaining Cloudflare’s ABR Analytics
In other words, the data is stored at multiple resolutions or sample intervals and the best solution is picked for each query.
The way ABR works is at the time of writing requests to ClickHouse, it writes the data in a number of tables with different sample intervals. For instance table_1 stores 100% of data, table_10 stores 10% of data, table_100 stores 1% of data and table_1000 stores 0.1% data so on and so forth. The data is duplicated between the tables. Table_10 would be a subset of table_1.
Demo
In Cloudflare, we use in-house libraries and tools to insert data into ClickHouse, but this can be achieved by using an open source tool – vector.dev
If you would like to test how log ingestion into ClickHouse works, you can refer or use the demo here.
Make sure you have docker installed and run `docker compose up` to get started.
This would bring up three containers, Vector.dev for generating vector demo logs, writing it into ClickHouse, ClickHouse container to store the logs and Grafana instance to visualize the logs.
Logs are supposed to be immutable by nature and ClickHouse works best with immutable data. We were able to migrate one of the critical and significant log-producing applications from Elasticsearch to a much smaller ClickHouse cluster.
CPU and memory consumption on the inserter side were reduced by eight times. Each Elasticsearch document which used 600 bytes, came down to 60 bytes per row in ClickHouse. This storage gain allowed us to store 100% of the events in a newer setup. On the query side, the 99th percentile of the query latency also improved drastically.
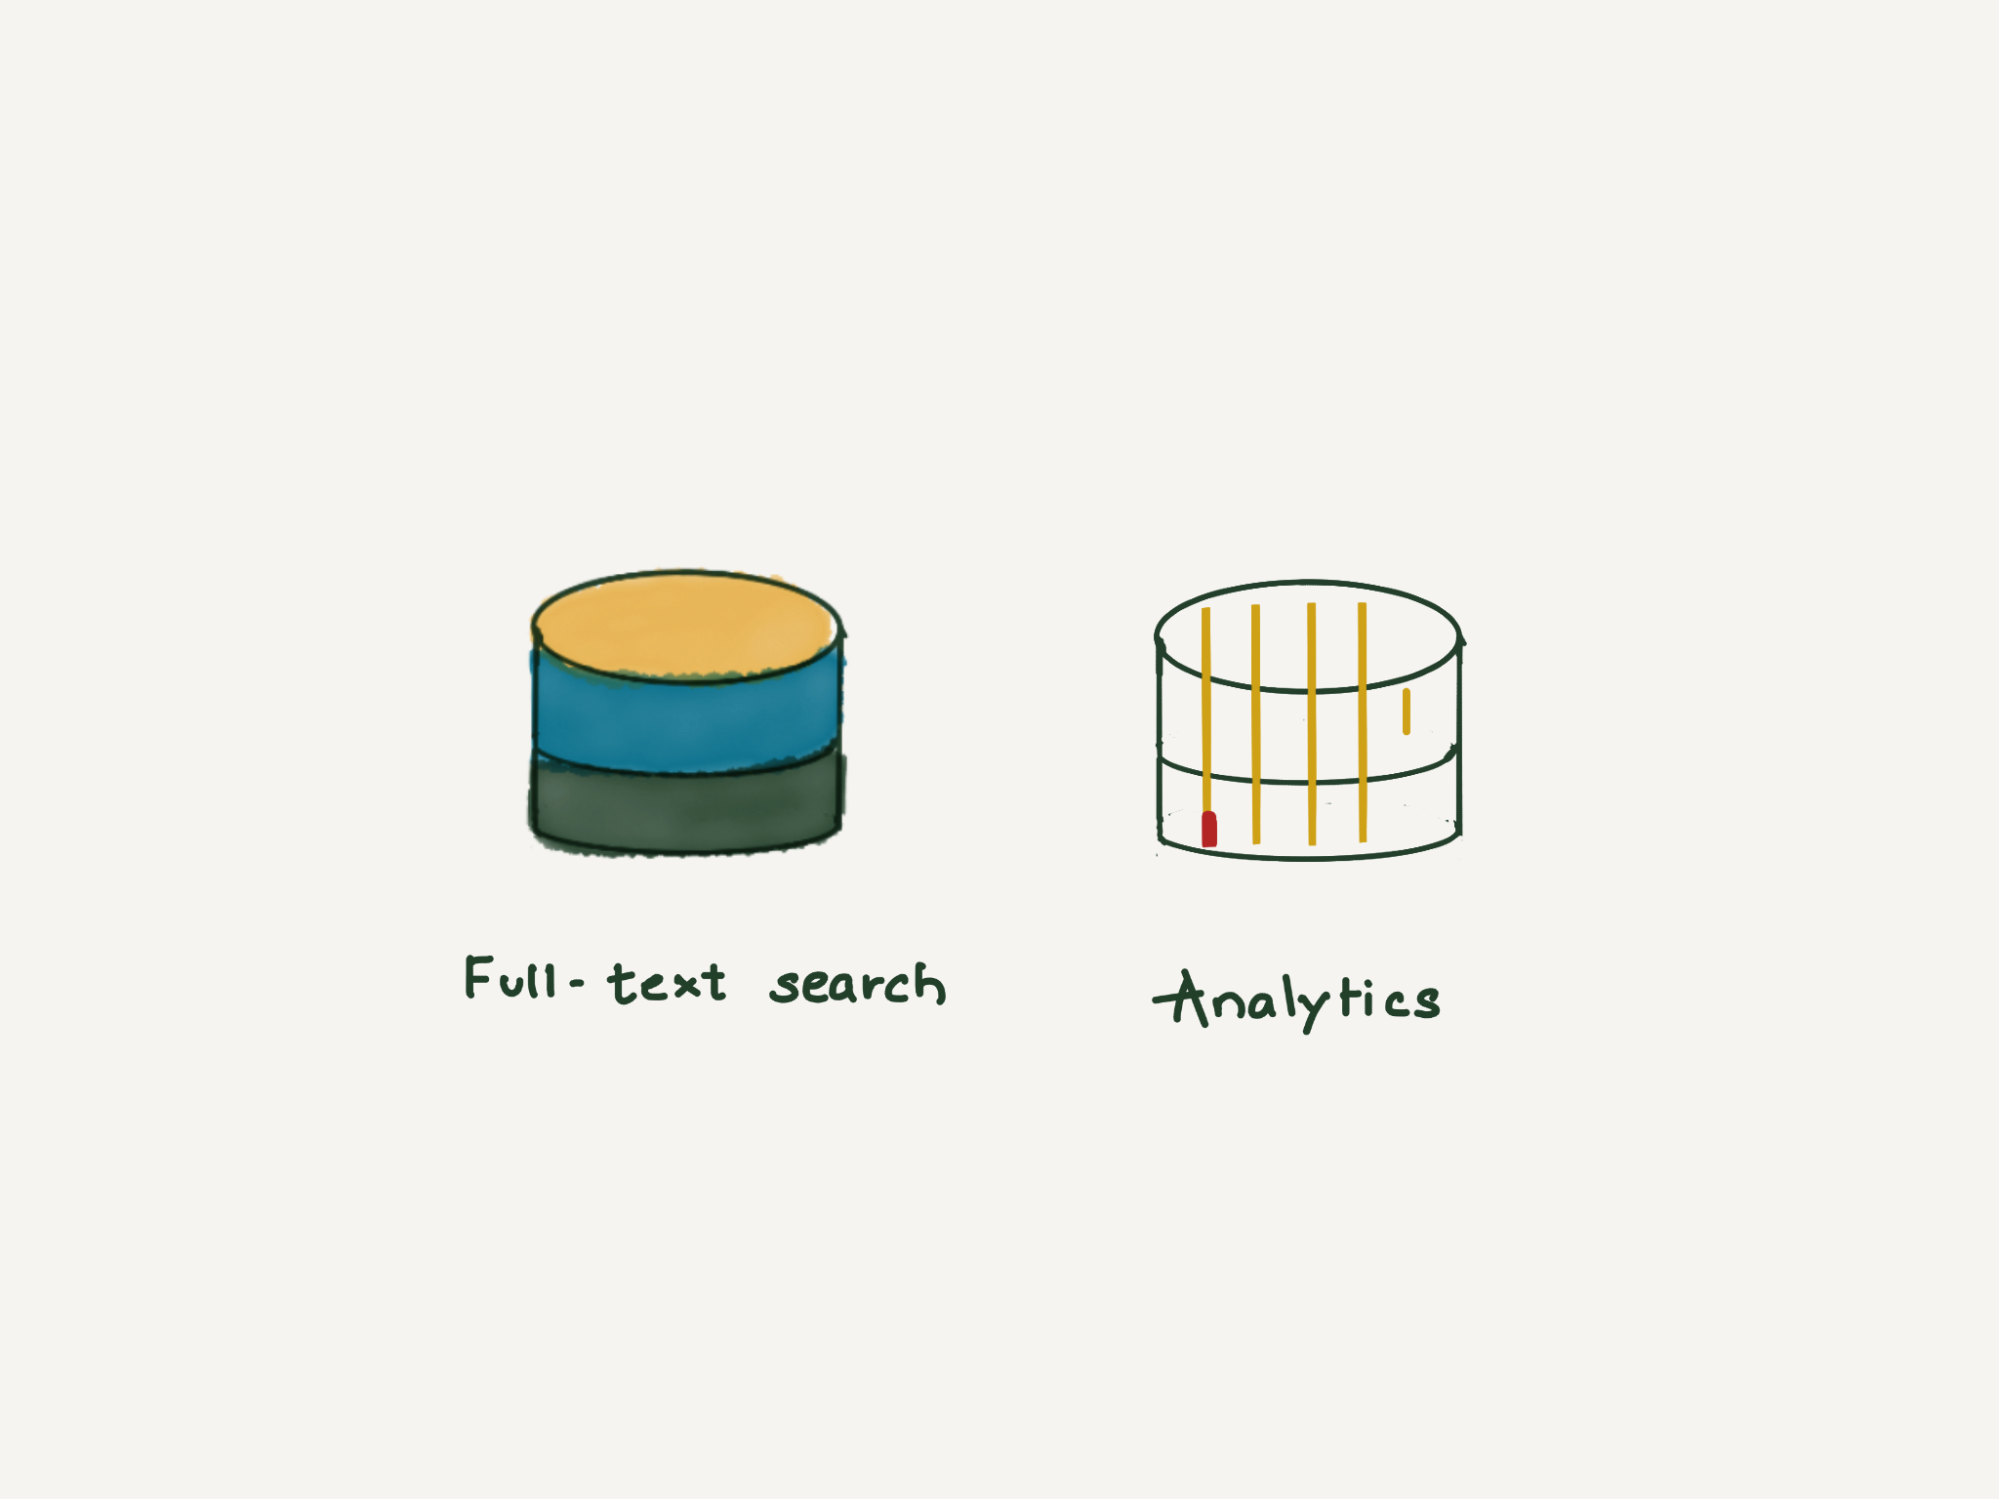
Elasticsearch is great for full-text search and ClickHouse is great for analytics.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.