Backblaze and Opti9 are partnering up to bring Backblaze B2 Cloud Storage to joint customers around the world as well as businesses in Canada who are required to keep their data within national borders.
The who and the why
Opti9 is the international leader in hybrid cloud solutions that delivers managed cloud services, application development and modernization, backup and disaster recovery, security, and compliance solutions to businesses around the world. By bringing Backblaze into their solution set, Opti9 is onboarding high performance, low cost cloud storage that works within all the solutions they provide.
Increasingly, companies seeking managed services support are demanding solutions made up of best-in-breed providers. While traditional cloud platforms work against this principle of interoperability, Backblaze and solution providers like Opti9 are committed to delivering cloud solutions without the limitations, complexity, and high pricing that are holding businesses back.
As Jim Stechyson, the President of Opti9 put it:
Backblaze and Opti9 focus on empowering businesses with the best cloud solutions available. Being able to integrate the high performance and low total cost of ownership of Backblaze’s object storage into our set of solutions will greatly enhance our ability to drive success for our customers.
How to get started
Interested resellers or customers who want to start working with Opti9 and Backblaze today can go to the Opti9 website. Check out our joint S3 compatible hot storage offering and book your demo to get started.
For customers based in Canada, Backblaze will be opening a new data region centered in Toronto in the first quarter of 2025. As part of the partnership, Opti9 will be the exclusive provider of server backup solutions in the Canadian channel for Backblaze B2 Reserve and the Powered by Backblaze program.
More about the new Backblaze data region in Canada
The new Canadian data region gives businesses the freedom to access Backblaze’s open, interoperable cloud solution, while still allowing customers to benefit from local storage and compliance. Located in Toronto, Ontario, the data center has been assessed and maintains a security program that addresses the requirements of SOC 1 Type 2, SOC 2 Type 2, ISO 27001, PCI DSS, and HIPAA. The region will be available to customers in the first quarter of 2025.
If you’d like to receive notifications about the data region opening date and when you can start storing data in Canada, you can sign up for the waitlist today.
Were you the person who stayed up until 2 a.m. to finish the group project? If you, like me, burned the midnight oil to save the team from utter failure, you suffered from a breakdown of shared responsibility. No one knew who was supposed to do what.
The same breakdown applies when you don’t fully understand the “shared responsibility model” that most software as a service (SaaS) platforms use when it comes to your data. You might assume that, because it’s in the cloud, your SaaS data is protected automatically. In reality, SaaS companies are only responsible for maintaining their uptime, not for retaining your files and critical information in case you need to get back online—and this has big implications for how you protect your data, ensure compliance, and optimize system performance.
Today, I’m diving into what this model means and how it affects how you use SaaS platforms.
What is the shared responsibility model?
The shared responsibility model defines the division of duties between a SaaS provider and its customers. It delineates which aspects of the system the provider manages and what tasks remain under the customer’s control. The primary goal is to clarify roles and reduce any ambiguity about who is responsible for certain aspects of security, data integrity, and system maintenance.
Defined roles, reduced ambiguity. That all sounds great to me, but what do SaaS providers actually take responsibility for? And what are you responsible for?
SaaS provider responsibilities
First and foremost, SaaS providers are responsible for ensuring that the application and its underlying infrastructure (servers, networking, data centers) are secure. This includes physical security, network protection, patching the platform, and overall system integrity. They typically guarantee a certain level of service availability, often formalized in a service level agreement (SLA). Downtime, system performance, and platform updates fall within the vendor’s scope.
Practically speaking, that means that they may not back up your data as often as you would like or archive it for as long as you need. SaaS vendors do not concern themselves with fully protecting your files. Most importantly, they may not offer a timely recovery option if you lose the data, which is critical to getting your business back online in the event of an outage.
Customer responsibilities
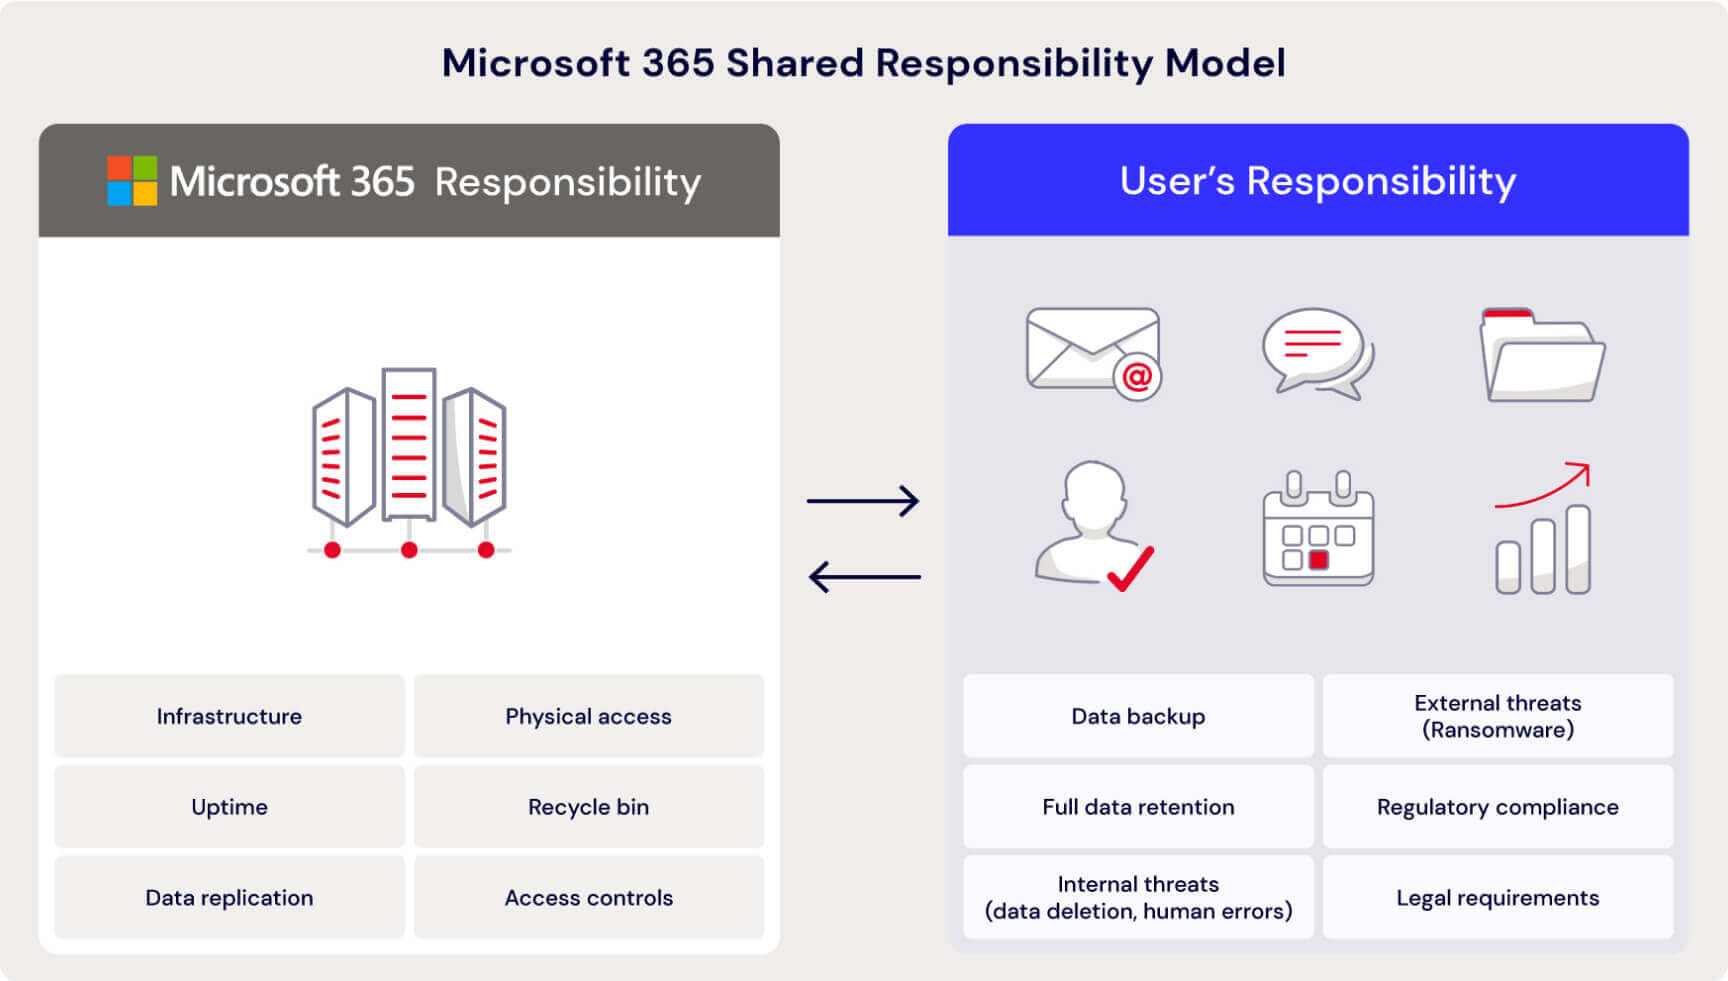
SaaS providers and cloud drives typically take responsibility for the security “of” the cloud, including the infrastructure that runs all of the services offered in the cloud. On the other hand, the customers are responsible for security “in” the cloud. This means customers must manage the security of their own data.
What’s the difference? Let’s use an example I’ve come across many times. If a user inadvertently uploads a ransomware-infected file to a cloud drive like Google Drive or OneDrive, the service might protect the integrity of the cloud infrastructure, ensuring the malware doesn’t spread to other users. However, the responsibility to prevent the upload of the infected file in the first place, and managing its consequences, falls directly on the user. In essence, while cloud drives provide a platform for storing your data, relying solely on them without understanding the nuances of the shared responsibility model could leave gaps in your data protection strategy.
Customer responsibilities include, among others:
Data protection: While the provider secures the infrastructure, you are responsible for securing the data you upload, manage, and store within the platform. SaaS platforms may replicate data and have redundancy safeguards in place to ensure you can access your data through the platform reliably, but they do not assume responsibility for their users’ data. It’s up to you to ensure your data is backed up according to your needs and policies.
Access management: You are responsible for controlling who has access to the SaaS environment. This involves creating strong user authentication processes, managing roles and permissions, and ensuring that the right people have access to the right information.
Compliance: Even if the SaaS vendor is compliant with say HIPAA or GDPR standards, you are also responsible for ensuring that you’re using the platform in accordance with those standards.
Here’s a graph that shows how shared responsibility breaks down for Microsoft 365 as just one example:
When the shared responsibility model matters
Unfortunately, I’ve found the shared responsibility model can create a false sense of security because understanding your responsibilities as a customer is often a process of elimination. SaaS responsibilities may be hard to track down, and when you can find them, they won’t say “you need to handle backups.” They’ll list what the provider handles, and all the rest is up to you.
When does this become important for you?
Security breaches: Many security incidents occur because of a misunderstanding of this model. For example, if a company assumes their SaaS provider is responsible for data encryption and user access control when, in fact, the company is, this can lead to critical vulnerabilities. A lack of clarity can expose businesses to data breaches, financial losses, and reputational damage.
Compliance issues: Regulatory compliance is another area that hinges on understanding shared responsibilities. Organizations that fail to implement required security measures or back up data properly can face fines, penalties, or legal consequences—even if the SaaS provider adheres to all necessary certifications.
Operational efficiency: Knowing where your responsibility starts and ends helps optimize how you use the platform. You can improve operational efficiency by focusing on the areas you control.
And, this gets even more complicated the larger your business and the more complicated your processes. So, if you have a business running on Google Workspace or M365, you can take something like emails and understand that Google is responsible for the email platform, but you should backup the individual emails themselves. But what about when you’re a media management company using best-of-breed tools for editing and collaboration, transcoding, asset management, and maybe even content delivery? All of those platforms have some responsibility in a shared responsibility model, and your job as a business is to understand where you are vulnerable—and then plug the gaps.
Navigating the shared responsibility model
So, what should you do with all of this information? In my experience, these are the biggest takeaways businesses can put into practice to successfully navigate the shared responsibility model:
Know your provider’s SLAs and security measures. Before adopting a SaaS solution, ensure you have a clear understanding of the vendor’s SLA and their security protocols. Understand the terms of their compliance with data privacy regulations, system availability, and disaster recovery.
What are Backblaze’s security and compliance protocols?
…is a question that would absolutely make sense for you to be asking. And I’m glad you did. Check out our Security and Compliance pages to learn more.
Educate your teams. Make sure that your internal teams are aware of their responsibilities in the shared model. Provide training on access control, data management, and security best practices to prevent accidental data exposure or misconfigurations.
Monitor and audit your usage. Set up regular audits to ensure that your organization is meeting its obligations under the shared responsibility model. Use tools to monitor access, detect unusual activity, and ensure data is being properly managed.
Make sure your backups are comprehensive. If you’re here, you’re probably well aware of this, but I can’t stress enough how important it is to back up your data, including data stored in cloud services like Microsoft 365, Google Drive, and OneDrive. Even if these services offer backups as part of the service, they may not meet your recovery needs.
How to approach the shared responsibility model
All this to say, you are ultimately responsible for backing up your data and files stored in SaaS clouds or cloud drives. The bottom line is that SaaS platforms’ top priority is to keep their own services running. By clearly understanding your role and responsibilities in this model, you can not only protect your data and ensure compliance, but also maximize the value of your SaaS investments.
It may seem like generative AI is the only game in town, or at least the only AI model worth paying attention to. But folks have been using AI models to do all kinds of things for years before ChatGPT, Claude, and Gemini came on the scene.
Today, I’m talking about the three different broadly defined categories of AI—classification, predictive, and generative—and what they’re good for.
Classification vs. Predictive vs. Generative AI Models: What’s the Diff?
Classification and predictive models have been foundational to AI for decades, powering applications like spam filters, cyber security tools, big data analysis, and demand forecasting. However, with recent advances, generative models like GPT and DALL-E have taken the spotlight, bringing up interesting existential (and legal) questions about the nature of creativity and creative work going forward. Understanding the distinctions and history of these models is key to grasping how AI continues to shape industries and innovation today.
Let’s see which category best applies to your particular problem.
AI classification models
A classification model is built to recognize, understand, and group data into preset categories. The model is fully trained using the training data and then evaluated using test data before being used to respond to unseen data. In general, such models infer answers for the current moment in time, for example, deciding whether an email is spam or phishing. In that case, the decision is based on comparing the incoming email to a model trained on previously classified email messages, both ones that the user has set or ones that the platform has. (The two are related, of course, as the platform’s filters often update to include aggregate user data.)
In business, classification models drive applications like spam detection, customer segmentation, and fraud detection. Healthcare uses classification models to diagnose diseases based on medical images or patient data. In finance, they help identify high-risk transactions. Social media platforms rely on these models to filter content, detect hate speech, and recommend posts. Overall, classification models are key to organizing large datasets efficiently and making decisions based on patterns, helping automate and optimize numerous industry processes.
AI prediction models
Predictive AI models utilize historical data, patterns, and trends to train the model, so they can be used to make informed decisions about future events or outcomes. Using Drive Stats as an example, we could theoretically build a model that, when given data about a particular drive model and failure rates, predicts the chance that a given hard drive will fail in the next 90 days. Predictive AI models typically require large amounts of data to be trained and are computationally expensive to generate.
Predicting Hard Drive Failure Rates with AI
Okay, we were being coy when we said “example.” Check out Andy Klein’s Tech Day 2024 presentation, “Predicting Hard Drive Failure Rates with AI” to see how this kind of predictive model works.
AI prediction models help predict customer behavior, sales trends, and demand, aiding in decision making and resource planning. In finance, these models are crucial for stock price forecasting, risk assessment, and credit scoring. Healthcare utilizes prediction models for patient outcome predictions, disease progression, and treatment effectiveness. They are also applied in weather forecasting, supply chain optimization, and energy usage management. By analyzing past data, prediction models provide insights that help organizations anticipate trends, make proactive decisions, and optimize performance across various industries.
Generative AI models
You know this one. Generative AI is about creating (sort of) new content. It uses neural networking, deep learning, and other techniques to infer and generate content that is based on patterns it observes in existing content all while mimicking the style and structure as requested. Image generators such as DALL-E and Stable Diffusion, and large language models like ChatGPT, Claude, and Gemini are easily accessible AI applications which have brought AI into the public eye.
Generative AI is at turns the thing that will revolutionize everything, a scary specter with near-sentience that will steal your job, or a big hallucinating fluke that tells you to put glue on pizza. There are some pretty cool use cases—for one, researchers are using generative AI for new drug discovery. But you’re most likely to run into generative AI in the following use cases: customer service chatbots, coding assistants, marketing support, and general business assistants that generate transcripts and summaries.
Unlocking the power of AI
Even with all the current hype around generative AI we are still in the early stages of development when it comes to AI systems given they are most useful in responding to queries based on the subject matter with which they were trained.
For example, an AI model trained to play chess might find playing checkers to be difficult. While the board, and number of players are the same, can a chess-playing AI model infer the allowed checker moves based on its understanding of chess? Even generative AI models like ChatGPT which are trained on a wide variety of subjects are still lacking a key ingredient to be truly useful to your organization: your data.
An AI chatbot, for example, isn’t going to perform the way you want it to without being powered by your organization’s data. And, how do you build an AI powered tool while keeping your private data private? We started to explore that very question in a recent webinar, “Leveraging your Cloud Storage Data in AI/ML Apps and Services.”
Tune in to learn more about the various ways AI/ML applications use and store data and get insights from our customers who leverage Backblaze B2 Cloud Object Storage for their AI/ML needs.
If you work in an industry with high performance and security demands like video surveillance, internet of things (IoT), and mobile applications, a new Backblaze capability could help your cloud workflows—Scalable Application Keys. This new capability enables you to generate application keys for your Backblaze B2 Cloud Storage Buckets at 150 times the current scale. When you need high volume, short-lived application keys to upload your data to cloud storage, you can’t tolerate bottlenecks—the Scalable Application Keys feature removes them.
Today, I’m digging into the challenges solved by Scalable Application Keys, the use cases where it has the most impact, and the benefits of the feature.
Jump to the docs
Check out our documentation for more information on Scalable Application Keys and how to work with them.
The challenges
Managing large volumes of data under strict security requirements sometimes requires using application keys programmatically to interact with cloud storage buckets. In the video surveillance industry, for example, you might upload massive amounts of video footage directly from security cameras to Backblaze B2, and you need to regularly refresh the application keys used by each of those cameras to maintain a robust security posture. However, this practice has a few unique requirements:
You can’t be hampered by rate limitations to generate the volume of application keys you need.
You need high key limits sufficient for the total volume of keys.
Throughput needs to be high to generate hundreds or thousands of new application keys simultaneously.
The irregular timing of key refreshes and the scale of operations can further amplify the problem, especially when hundreds or thousands of devices request new keys at the same time.
The solution: Scalable Application Keys
With the introduction of Scalable Application Keys, Backblaze B2 customers can generate and refresh keys at significantly higher volumes and throughput—without hitting hard limits on the number of keys. This feature is designed to accommodate the unique requirements of customers who need:
High key throughput: Create keys at scale, even when thousands of devices need new keys simultaneously. You can create up to 10,000 keys per minute.
Unlimited key generation: Scale without interruption—there’s no hard cap on the number of application keys that can be generated.
Short-lived keys: Easily generate keys with very short lifespans, enhancing security without compromising functionality.
S3 compatibility: Maintain support for the Backblaze S3 compatible API, allowing you to avoid costly firmware upgrades on your devices.
Real-world applications
This feature is particularly beneficial for customers with many endpoints that all upload to Backblaze B2 cloud individually through the S3 Compatible API. For example:
Video surveillance: Companies with large networks of security cameras can now easily refresh keys for each device frequently. When you operate tens of thousands of cameras that record sensitive footage, you need to be able to refresh application keys regularly to maintain security. With Scalable Application Keys, you can handle refreshes efficiently and continue scaling the number of cameras in operation without worry.
Mobile applications: Developers of mobile apps that store data in B2 Cloud Storage can generate unique keys for each user’s device. This is especially useful for apps that rely on user-generated and user-uploaded content, where each end device needs its own application key.
IoT devices: Businesses managing large fleets of IoT devices, where each device needs a unique and regularly refreshed application key, can ensure secure, individualized access to cloud storage.
Benefits of Scalable Application Keys
Enhanced security:
Frequent key rotation becomes feasible at scale, significantly reducing the risk of unauthorized access.
Short-lived keys minimize the window of vulnerability if a key is compromised.
Customers can implement best practices for key management without extraneous components that could cause performance penalties.
Operational flexibility:
Easily manage key generation for large numbers of devices, from thousands to millions.
Accommodate sudden spikes in key requests, such as during system-wide updates or resets.
Adapt to varying usage patterns throughout the day without hitting rate limits.
Cost effectiveness:
Avoid expensive firmware upgrades by continuing to use the S3 Compatible API.
Eliminate the need for complex workarounds or additional infrastructure to handle key management.
Scalable Application Keys not only solves existing limitations but also future-proofs your workflows by providing the flexibility and performance needed to scale without restriction.This feature allows you to securely manage access to B2 Cloud Storage, no matter the scale of your operations.
Ready to get started?
This feature is available upon request. If you’re an existing Backblaze B2 customer and want to get access to this capability, please contact our Support team to request access.
New to Backblaze? Contact our Sales team to learn more about how Scalable Application Keys can benefit your business and how to get started.
Once this feature is enabled, you can generate application keys at scale. Check out the documentation for more on how to use the feature.
What next?
Are you leveraging Scalable Application Keys to build more efficient and performant workflows? Share how it’s working for you so other organizations and developers can benefit from what you find. If you have any questions or feedback, please don’t hesitate to reach out to us.
AI is everywhere—powering chatbots, generating images, even deciding what you binge watch next. It’s no wonder businesses of all sizes are feeling compelled to jump on the AI bandwagon. But before you get swept up in the AI hype, here’s the question you need to ask: Is AI right for your business and the problem you’re trying to solve?
Where AI truly becomes a change agent is when it is powered by your organization’s data to deliver relevant, insightful, and actionable observations to you in a timely manner. The reality is, while AI is really cool, without your unique data it provides your organization few competitive advantages. Of course, releasing proprietary, or even sensitive, information to a robot connected to the internet can be risky—and you want to make sure your (and your clients’) information doesn’t end up in surprising places.
But just because everyone’s talking about AI doesn’t mean it’s the magic bullet for every problem. Like any strategic investment, it takes careful consideration. So, before you hand over your data to a machine, let’s explore whether AI is really what your business needs—or if it’s just another shiny object in the tech landscape.
Where do I start?
Today, many organizations are somewhere along the AI/ML path. Most are experimenting with AI, some are actively building applications, and a handful have successfully deployed a solution. Like any other project, before you start trying to use AI in your organization, the first thing you should do is define the problem you are trying to solve. Only then can you determine if you really need AI as a part of the solution.
Ask yourself the following questions about the project. If you answer yes to all four items, the project is AI-worthy:
1. Do you want AI to replace tedious, repetitive tasks?
Start by identifying the business problem in specific, measurable terms. Determine the scope of the problem, its frequency, and the impact it has on your business. Is it recurring and time consuming? If the problem is complex, repetitive, or data-intensive, it might be suitable for AI.
2. Do you want to use AI because you can’t consistently apply a set of logical rules to answer the questions at hand?
If the problem involves large amounts of data that is difficult to process manually where the answer is derived by combining and weighing multiple factors, it may be a candidate for an AI-based solution. On the other hand, just because it can be automated doesn’t mean you need an AI solution—AI is expensive in terms of power and processing resources. If you’re running a simple routine task over and over, you might be just as well off using traditional programming methods. But, when you’re solving a complex task, you need a structure that is not a strict binary, and that’s when you might want to use AI.
3. Will you use AI for problems that humans can solve, but AI can solve much faster?
AI should help your organization solve problems it finds extremely difficult or nearly impossible to solve otherwise. AI excels at tackling complex problems that overwhelm traditional methods, such as processing vast amounts of data, recognizing intricate patterns, or making real-time predictions. If your business is facing challenges that manual processes or standard software can’t handle effectively, AI can step in to provide powerful, scalable solutions that would otherwise be out of reach.
But remember, AI should work with you, not against you. Understand how AI will integrate into your workflow and whether it aligns with your overall business strategy to avoid creating unnecessary complications or disrupting ongoing operations.
4. Do you intend for AI to increase productivity of a function or group?
Most AI projects are productivity based, even those that seem otherwise. Even AI projects aimed at improving customer experiences, like personalized recommendations, ultimately enhance productivity by streamlining interactions and reducing manual effort. At their core, most AI implementations are designed to automate tasks, optimize processes, or extract actionable insights, all of which drive greater efficiency and cost savings. And, that means you need to analyze the potential return on investment (ROI).
AI integration requires an investment in technology, data management, and often specialized personnel. Weigh the cost of implementing AI against the potential benefits it could bring. Will it save time or reduce costs? By how much? If the financial or productivity benefits outweigh the costs, AI may be a worthwhile investment.
Where to next?
Clearly defining the problem and deciding if it’s suitable for an AI-based solution is really just the first step. Once the problem is defined, you open up another set of questions around whether and how to implement it. Do you have the right data, resources, and expertise to support an AI solution? How will it integrate with your systems? How will you measure success? The answers to all of these questions should absolutely inform your decision-making, but understanding if you’re applying AI to the right problem is your starting point. Without that, you’re using a sledgehammer to crack a nut, so to speak.
You probably won’t notice a little asterisked footnote tucked at the bottom of the page the first time you read through a cloud storage vendor’s pricing tables. You probably won’t notice it the second or third time either. But you’ll definitely notice it when your bill comes in with charges for data you thought you deleted weeks ago.
That footnote explains an often overlooked challenge to your budget: minimum data retention periods. These policies, used by cloud providers like AWS, Azure, Google Cloud, and Wasabi, can lead to unexpected cost increases and complicated data management strategies.
Today, I’m breaking down cloud storage retention minimums and common scenarios where they directly impact storage budgets and data management policies.
What are minimum data retention periods?
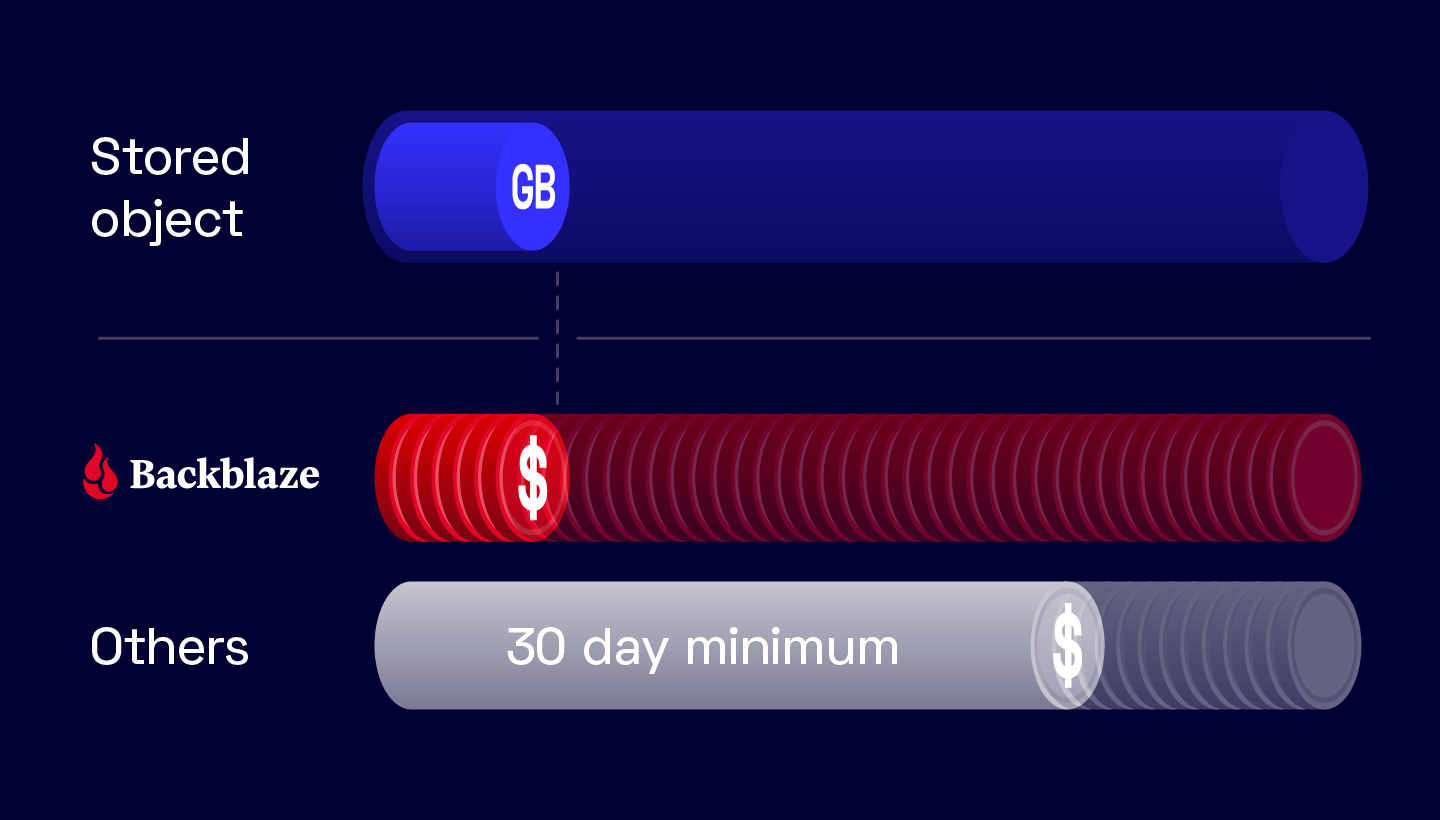
Retention minimums specify the minimum amount of time that data must be stored before it can be deleted, overwritten, or moved to a different storage tier without incurring additional charges.
Cloud storage providers with multiple tiers like AWS or Google Cloud use minimum retention policies to ensure that customers cannot frequently move data between storage tiers to exploit lower-cost storage classes for short-term storage. For cloud providers that have a single class of storage, these policies allow providers to stabilize their resource usage and maintain predictable pricing structures.
Minimum retention periods can vary significantly between providers, and even between different storage tiers offered by the same provider. For example, AWS S3 Standard has no minimum retention period, but S3 Standard-IA has a 30 day minimum, Glacier has a 90 day minimum, and Deep Archive has a 180 day minimum.
Despite their significance, information about these retention periods is often buried in the fine print of service agreements or technical documentation.
What are delete fees?
Delete fees are a direct consequence of deleting or moving files before the retention minimum is met. Cloud providers charge these fees to ensure that the infrastructure allocated for the data is compensated for the resources it would have otherwise used during the retention period. This fee is typically prorated, representing the remaining days in the retention period that the data was meant to occupy in a storage class.
The terms “delete fees,” “minimum storage duration,” and “minimum retention fees” all refer to a similar policy.
How are delete fees incurred?
Early deletion fees can be triggered by various actions, not just the obvious deletion of files. Some examples include:
Moving data from a higher-cost tier to a lower-cost tier before the minimum retention period has been met: This scenario often catches organizations off guard when they attempt to optimize costs by transferring infrequently accessed data to a cheaper storage class.
Overwriting existing files: When a file is overwritten, the cloud provider typically treats this as a delete operation followed by a new write operation. If the original file hasn’t met its minimum retention period, the organization may be charged for the remaining time, even though they’re still using the same amount of storage space.
Implementation of automated lifecycle policies: Many organizations set up rules to automatically move or delete data based on its age or access patterns. However, if these policies don’t account for minimum retention periods, they can inadvertently trigger early delete fees on a large scale.
Renaming files or folders: Even seemingly benign actions like renaming files or folders can sometimes be interpreted as delete-and-rewrite operations by certain cloud storage systems, potentially triggering these fees.
Additionally, in multi-user or multi-team environments, lack of communication about retention policies can lead to unexpected charges. One team might delete or move data without realizing the financial implications for the entire organization.
The financial impact of minimum data retention periods
Minimum data retention periods, particularly in cold storage tiers, can have significant impacts on IT budgets. What may have seemed like a cost-saving storage tier can actually increase expenses when operations require frequent deletions or movements of data before the minimum retention period is over. But even in hot storage, these policies can unexpectedly inflate overall costs.
To illustrate the real-world impact of retention minimums, let’s examine a few common scenarios:
1. Backup strategy
Let’s say you have a 30 day backup strategy for your critical infrastructure, and you opt for Wasabi object storage to save costs vs. AWS. You plan to keep a month’s worth of backups in the cloud and will then replace them with the newer backups.
Wasabi’s minimum retention policy is 90 days for its Pay as You Go storage (and 30 days for its Reserved Capacity Storage).
You store an initial 50TB of backups in Wasabi on Day 1. On Day 31, the older backup is deleted and replaced with the newer backup. So, you incur costs for 30 days of Timed Active Storage (50TB) and 60 days of Timed Deleted Storage (50TB). These charges are incurred every time the backup is replaced.
With Wasabi’s Pay as You Go storage, your monthly bill will look like this:
50TB x $6.99/TB/month x 3= $1048.50
We multiply by 3 because the 90 day minimum retention policy equals three months’ time. One of those you’ve actually stored for, and the other two are because you’ve replaced your backups with the new ones.
Compare this to Backblaze B2 Cloud Storage, which has no minimum retention policy and costs $6 per TB/month for its Pay as You Go storage:
50TB x $6/TB/month = $300
The minimum retention policy effectively triples the anticipated storage expenses. When scaled across multiple backup sets or extended periods, the impact on the IT budget can be substantial.
Delete fees in the real world: California university switches to Backblaze to eliminate surprise bills from Wasabi
Cal Poly Humboldt thought they understood cloud storage provider Wasabi’s pricing, but each month brought unexpected charges for deleted data due to Wasabi’s minimum storage retention policies. This, in turn, caused a chain reaction of calls from the procurement office, buying extra capacity, and then modifying the system to try to avoid further bills. To silence the monthly fire alarms, they switched to Backblaze.
With no retention minimums, Cal Poly Humboldt now knows exactly what their Backblaze costs will be up front. The move was so smooth that they migrated another 100TB from Google’s no-longer-free tier for educational institutions and plan to scale their storage to over a petabyte to back up and safeguard research data.
2. Application storage
In application storage use cases, retention minimums can impact cloud spend significantly when the data has a short lifecycle. Applications with high transaction volumes—such as e-commerce, user-generated content applications, or surveillance platforms—frequently upload and delete as part of their daily operations.
For example, most video surveillance platforms may only need 30 days of history for footage that’s been uploaded and processed, so something like a 90-day retention period doesn’t make financial or operational sense. E-commerce customers can also be affected; these businesses have users that frequently upload and delete content to manage storefronts, creating unpredictable data usage patterns. In these cases, you are at the mercy of your end users—if users churn through files quickly you will pay the retention penalties.
3. Video production
Retention minimums also affect video production workflows particularly when you need to make revisions once a project has been archived in cold storage—a common workflow many studios and broadcasting agencies use to get more affordable storage rates for seldom-accessed data.
Whether due to last minute changes in branding, edits to visuals, or adjustments to sound, the project needs to be pulled from storage for further modification. Because the files were moved to colder storage under a 90 day retention policy, accessing and modifying them before that period ends can trigger significant early delete fees.
If you routinely archive files immediately after a project completes anticipating that no further changes will be required, these early delete fees can add up quickly.
The hidden complexities of minimum data retention periods
Retention minimums can significantly impact your bottom line. These policies, often buried in the fine print, can lead to unexpected costs and complicate data management strategies across various industries.
Understanding the nuances of minimum data retention periods and their associated costs is crucial for developing an effective and economically sound cloud storage strategy. It enables organizations to make more informed decisions, avoid unexpected expenses, and better align their storage choices with their specific data management needs and budget constraints.
No one likes being left out in the cold, least of all your data. With Backblaze B2 Event Notifications—now generally available—you can receive real-time notifications about object changes. That means that you can build more responsive and automated workflows across best-of-breed cloud platforms, saving time and money and improving your end users’ experiences. And, you can be alerted to changes in your data that may speed time to action.
Here’s how it works: With Backblaze B2 Event Notifications, any data changes within B2 Cloud Storage—like uploads, updates, or deletions—can automatically trigger actions in a workflow, including transcoding video files, spooling up data analytics, delivering finished assets to end users, and many others. Importantly, unlike many other solutions currently available, Backblaze’s service doesn’t lock you into one platform or require you to use legacy tools from AWS.
So, to businesses that want to create an automated workflow that combines different compute, content delivery networks (CDN), data analytics, and whatever other cloud service: Now you can, with the bonus of cloud storage at a fifth of the rates of other solutions and free egress.
Key capabilities
Flexible implementation: Event Notifications are sent as HTTP POST requests to the desired service or endpoint within your infrastructure or any other cloud service. This flexibility ensures seamless integration with your existing workflows. For instance, your endpoint could be Fastly Compute, AWS Lambda, Azure Functions, or Google Cloud Functions, etc.
Event categories: Specify the types of events you want to be notified about, such as when files are uploaded and deleted. This allows you to receive notifications tailored to your specific needs. For instance, you have the flexibility to specify different methods of object creation, such as copying, uploading, or multipart replication, to trigger event notifications. You can also manage Event Notification rules through UI or API.
Filter by prefix: Define prefixes to filter events, enabling you to narrow down notifications to specific sets of objects or directories within your storage on Backblaze B2. For instance, if your bucket contains audio, video, and text files organized into separate prefixes, you can specify the prefix for audio files in order to receive Event Notifications exclusively for audio files.
Custom headers: Include personalized HTTP headers in your Event Notifications to provide additional authentication or contextual information when communicating with your target endpoint. For example, you can use these headers to add necessary authentication tokens or API keys for your target endpoint, or include any extra metadata related to the payload to offer contextual information to your webhook endpoint, and more.
Signed notification messages: You can configure outgoing messages to be signed by the Event Notifications service, allowing you to validate signatures and verify that each message was generated by Backblaze B2 and not tampered with in transit.
Test rule functionality: Validate the functionality of your target endpoint by testing Event Notifications before deploying them into production. This allows you to ensure that your integration with your target endpoint is set up correctly and functioning as expected.
Retries: Event Notifications are automatically re-sent if the initial delivery attempt fails. This feature increases the reliability of Event Notifications by ensuring that temporary issues do not result in missed events, thus maintaining the integrity of your event-driven workflows.
Delivery: Event Notifications are designed for the at-least-once delivery guarantee to ensure Event Notifications are delivered reliably, even in the presence of network or system failures.
Versatile use cases
This past April, we announced Event Notifications in preview, and folks have put Event Notifications to work in some incredible ways. Today, we’re sharing some of the key use cases that came out of the preview to simplify your own workflows so you can focus on extracting insights from your data, rather than managing the logistics of data processing.
Automated media processing
Video transcoding: Many customers use Event Notifications to automate their video transcoding workflows. When a new video is uploaded to a Backblaze B2 Bucket, an Event Notification can trigger a transcoding process to generate all videos in the desired format.
Image processing: Similarly, customers also use Event Notifications to set up automated image processing pipelines, such as generating thumbnails or applying filters when new images are added to a Backblaze B2 Bucket.
Media processing is not limited to video transcoding or image processing. It can be extended to any other media processing workflow, minimizing the number of steps in the workflow.
Backup monitoring
Customers can receive notifications when backups are successfully uploaded to a Backblaze B2 Bucket with Event Notifications, providing peace of mind and ensuring data protection. Whether you want to track your nightly or monthly backups, you can get a notification when they are completed.
Presigned URL monitoring
Using a presigned URL is a standard way to share a file without giving the full access to your Backblaze B2 Bucket. Customers are using Event Notifications to know when their clients upload files via presigned URLs to Backblaze B2. They can get a callback to confirm that the upload is complete.
Security and access control
Unauthorized access detection: Customers are using Event Notifications to track access to highly confidential video files and report back to their clients as needed. Event Notifications help them detect any unauthorized access and take immediate action.
Audit trails: Some customers are using Event Notifications to create a detailed audit log of supported bucket activities through Event Notifications, which is useful for their compliance and security purposes.
Anomaly/malware detection: Event Notifications can strengthen security by detecting unusual access patterns, like malware that deletes or overwrites backups, by getting notifications of changes to Backblaze B2 Buckets.
Integration with external systems
Database synchronization: Customers use Event Notifications to keep databases in sync with the state of their Backblaze B2 Buckets. It’s critical to ensure data consistency across systems as their applications run on the databases.
Document management system: Some customers use Event Notifications with a workflow system to track document revisions, uploads, and deletes, or to notify team members when specific documents are uploaded or deleted.
Analytics and reporting
Performance analytics: Some customers use Event Notifications to monitor their backup performance and completion times, helping to optimize their data management strategies.
Usage tracking: Event Notifications can help track storage consumption by individual users or projects, facilitating better resource management and cost allocation.
These are just a few of the use cases our preview customers shared with us, and the sky is truly the limit for ways Event Notifications can empower you to simplify and streamline your workflows.
Ready to get started?
For existing customers working with a Backblaze account manager, Event Notifications is enabled for you today. If you need assistance, your account manager is happy to help.
For existing customers who are not currently working with an account manager, please contact our Support team to request access.
New to Backblaze? Contact our Sales team to learn more about how Event Notifications can benefit your business and how to get started.
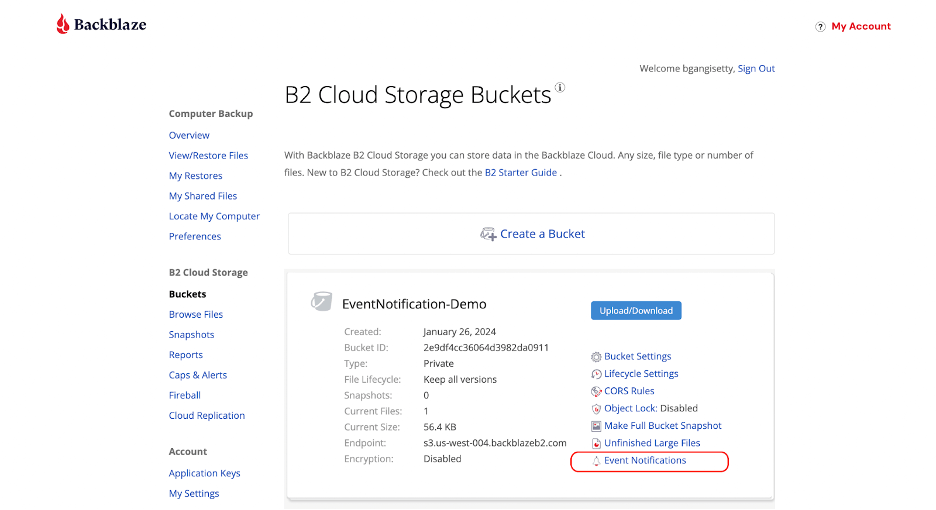
Once Event Notifications is enabled on your account, log in to your Backblaze B2 account, navigate to the Buckets page, and click on the Event Notifications section. From there, you can set up notification rules for the events you want to track or configure notifications through our API.
Please do share how you’re leveraging Event Notifications to build more efficient, automated, and responsive workflows so that other organizations and developers can benefit from what you find. If you have any questions or feedback, please don’t hesitate to reach out to us.
Video and data are the lifeblood of sports teams and leagues, fueling everything from fan engagement to game analysis.
To keep operations running smoothly, sports teams need to ensure that assets are stored securely, managed cost effectively, and kept ready for quick access. Cloud storage is increasingly part of sports teams’ data management playbooks, integrating with existing workflows and media tools so that teams can stay sharp and keep fans engaged.
Let’s break down what’s driving data growth in the sports market, use cases for cloud storage, and four best practices you can use to adopt cloud storage in a hybrid approach.
What’s driving data growth for sports teams?
During a given game, teams typically capture multiple camera angles, including sideline and aerial views, along with player-specific footage. Inside the stadium, teams use video and data to create an immersive fan experience, with big-screen displays and other screens showing player profiles, replays, real-time stats, and more. The action doesn’t stop there. Live feeds and exclusive content delivered on mobile devices add interactivity, bringing the game closer to the audience.
Sports teams generate a massive amount of video and image data during a game. As an example, a given professional sports game may involve around 10–12 cameras, and each can generate several terabytes of high-definition (high-def) footage over the course of the game.
High-def video files can range from 1–3GB per minute of footage, meaning a two to three hour game with multiple cameras might produce dozens of terabytes. On top of that, teams use high speed cameras for slow motion analysis, which further increases the data volume. When considering still images from different angles and high-resolution (hi-res) formats, the overall image and video data generated per game can easily reach 10–20TB or more, depending on the resolution and frame rates used.
How sports organizations take advantage of cloud storage: Key use cases
Given the massive data growth in sports organizations, many teams rely on cloud storage to help them store, manage, and use that data effectively. Here’s how they do it.
Replacing aging on-premises systems
Professional sports teams have long relied on on-premises storage like LTO tape systems or servers to keep their game footage, player performance data, and other critical content safe. But as time goes on, these systems become harder to maintain, prone to breakdowns, and outmatched by the growing volume of data. As media and data continue to pile up, teams need storage that can scale fast without requiring a major investment in new infrastructure.
By using cloud storage—typically through a hybrid infrastructure that utilizes both cloud and on-premises systems—sports organizations can off-load some of the hassle of maintaining and upgrading aging physical systems. Cloud storage eliminates the need for constant hardware replacements, freeing up IT teams to focus on more strategic plays.
Eagles retire LTO, drafting up an active cloud archive
With multiple championships behind them, the Philadelphia Eagles had decades of incredible content to mine and protect, but they needed to draft and train up some new technical assets to stay in contention. They retired their LTO-6 system and shifted hundreds of terabytes off of their storage area network (SAN) to a true cloud archive in Backblaze B2 Cloud Storage. Check out their game plan for protecting data and improving media workflows in the cloud.
Enhancing video management and distribution
By implementing cloud storage for hot archives, a league or team can store all video content in a centralized repository that offers instant access from anywhere, especially when paired with cloud-friendly media asset management (MAM) tools.
Cloud storage simplifies the process of sharing large video files with players, broadcasters, and media outlets, boosting an organization’s ability to monetize its content.
Backblaze B2 Live Read changes the game
Advanced services like Live Read give teams the ability to access, edit, and transform media as it’s uploaded. This speeds up content retrieval for analysis, editing, and distribution, making it especially useful on game days, when quick access to video and analytics can influence real-time decisions and help create up-to-the-minute content.
Business continuity and disaster recovery
Keeping sensitive data and high value media safe is nonnegotiable for sports organizations. A natural disaster, cyberattack, data breach, or other threat to stored data and media can cause days or weeks of downtime, making critical assets inaccessible and leading to significant operational disruptions.
Teams are using cloud storage to create geographic redundancy that ensures that data stays secure and recoverable even in the event of a local disaster. Tools like Object Lock add an extra layer of protection, making sure that data can’t be tampered with or deleted.
Integrating AI capabilities
AI is employed by sports teams to automate video analysis and content tagging, create highlight reels almost instantly, and scale personalization efforts.
Using the cloud to implement AI for sports media makes sense thanks to its scalability, processing power, and accessibility. Cloud platforms can handle vast amounts of video data and provide the computational resources necessary for AI-driven tasks like real-time analysis, high-speed editing, and video rendering. The cloud also enables collaboration across multiple locations, allowing teams, coaches, and analysts to access and process data seamlessly. Cloud-based AI is cost efficient, as teams only pay for the resources they use, avoiding the high costs of maintaining dedicated on-premises AI infrastructure.
Leverage video understanding with Twelve Labs
Twelve Labs’ video understanding platform allows you to build AI functionality into your workflows, giving you the ability to automate metadata tagging and search video archives with natural language. Check out how it integrates with cloud storage in Backblaze B2.
Optimizing costs
As traditional storage systems scale up, they can become prohibitively expensive—not only in direct costs, but also in ongoing maintenance and management. Cloud storage is inherently scalable, capable of handling growing volumes of content and data without breaking the bank.
Cloud storage helps sports teams optimize data storage costs by offering scalable, flexible pricing models that align with their data needs. Depending on their needs, teams can choose to pay for the exact amount of storage they use or to leverage capacity-based storage plans, but in either case, they’ll avoid the need for expensive on-premises hardware that often requires over-provisioning.
With cloud storage, teams can dynamically scale storage up or down based on their requirements—like during the season when video data surges—though it’s essential to consider things like egress fees in cost calculations. Backblaze, for example, includes 3x free egress, which can reduce costs significantly.
Hybrid cloud storage for sports teams
Many organizations take a phased approach in embracing cloud storage, or choose to continue leveraging on-premises storage infrastructure along with new cloud storage resources in a hybrid model. As with any deployment of new technology, this process is best undertaken with a thoughtful game plan.
Four best practices for adopting hybrid cloud storage
1. Assess your current infrastructure
Begin by auditing the on-premises storage systems you currently rely on to maintain team footage and data. Knowing where your storage infrastructure falls short, you can set clear objectives for a hybrid solution, such as increased accessibility or more cost-effective scaling options, and then map out your shift to the cloud. Evaluate capacity, performance, and scalability limits to help identify pain points (e.g., slow access to media files, high costs) and inform prioritization of the data or content that should move to the cloud.
2. Prioritize media for migration
Depending on your goals, you’ll prioritize different media for a cloud migration. For example, if your goal is to modernize your archive and make it more accessible for monetization, it makes sense to move archives off LTO to an active cloud archive. On the other hand, if your goal is streamlining remote workflows, your production data is likely first up for a cloud migration while you can maintain on-premises solutions for your archives as long as they’re serving your needs.
3. Leverage hybrid storage as a transition stage
With a cloud storage platform that integrates smoothly with existing on-prem storage and applications, you are well positioned to implement a hybrid cloud solution. A hybrid storage model allows you to shift operations to the cloud gradually, without the need for an abrupt overhaul. As you navigate this transition, your team can begin to take advantage of cloud scalability and flexibility without abandoning familiar workflows or compromising performance.
4. Establish clear data management policies
Structured data management helps prevent inefficiencies, such as duplicated or misplaced files, and ensures that storage solutions align with operational needs. Create clear policies for where media and data are stored (on-prem or cloud), when and how each should be moved, and which users have access (and at what level).
Preparing for the future
As sports organizations continue to generate and rely on massive amounts of video and data, cloud storage is increasingly becoming a strategic necessity. By embracing cloud storage, teams and leagues can increase their efficiency, improve fan engagement, enhance performance analysis, and ensure operational continuity—all while optimizing costs and future-proofing their infrastructure. The result? More streamlined, secure, and scalable storage that supports long-term success on and off the field.
Ransomware is now a billion dollar industry, and one of the best things any business can do to protect its bottom line is to back up. But, it’s important to remember that backups are only the first step in the process—when you are affected by a ransomware attack, natural disaster, or even human error, you’ll then need to restore.
As your business scales and becomes more complex, so does your backup and restore process. You’ll have more types of data to restore, on more networks and devices, with more people involved at every step of the way.
The best way to make sure your backups are effective? Test them regularly. Let’s talk about why and how.
Good reasons to test your backups
By regularly testing your backups, you can improve your chances of a successful recovery and minimize the impact of data loss. Here are several reasons why regular backup testing is crucial:
Data integrity verification: Testing ensures that your backups are accurate and complete. A failed test might reveal corrupted files or missing data that could lead to significant losses.
Recovery process validation: By simulating the recovery process, you can identify potential bottlenecks or issues in your restoration procedures. This ensures that you can quickly and effectively recover your data in case of a disaster.
Disaster readiness assessment: Regular testing helps you assess your overall disaster recovery plan. It reveals any weaknesses or gaps that need to be addressed to ensure business continuity and to meet recovery time objectives.
Compliance adherence: Many industries have strict data retention and backup requirements. Testing helps you demonstrate compliance with these regulations.
Cyber insurance standards:Cyber insurance adoption is increasingly important for businesses, and many cyber insurance providers focus both on helping their clients prepare for ransomware attacks and recovery after the fact. As a result, many require regular backup verification testing and reporting.
Peace of mind: Knowing that your backups are reliable and tested can provide peace of mind and reduce stress during a crisis.
Early detection of issues: Testing can uncover problems with your backup software, hardware, or processes early on, allowing you to address them before they lead to more significant consequences.
In short, regular backup testing not only confirms that your data is properly backed up, but also ensures that you’re meeting recovery point objectives (RPO), have key features like immutability configured properly, and supports overall business objectives.
Ransomware and backups
In addition to the above reasons, it’s important to note the growing trend for ransomware bad actors to specifically target backups. Veeam’s 2024 Ransomware Trends Report shows that 96% of attacks focus on backup repositories with the bad actors successfully affecting the backups in 76% of cases. Elsewhere, Sophos reports in instances where backups were compromised, ransomware demands doubled, and recovery costs were eight times higher.
How to test your backups
Testing device backups is crucial to ensure data integrity and recoverability in case of loss or damage. Here are some effective methods:
1. Manual restoration tests
Regularly restore files: Select random files from your backup and restore them to a different location. Verify that the restored files are identical to the original files.
Test system restore: If your backup includes system images, periodically restore them to a separate partition or virtual machine to ensure they function correctly.
2. Automated testing tools
Backup software features: Many backup solutions offer built-in testing features. These tools can automatically verify the integrity of your backups and alert you to any issues. Restore services like Cloud Instant Backup Recovery can also provide valuable insight and support before, during, and after ransomware events.
Third-party verification tools: Consider using specialized tools designed for backup verification. These tools can provide more in-depth analysis and reporting.
3. Simulated disaster scenarios
Create a test environment: Set up a simulated disaster environment, such as a corrupted hard drive or a system failure.
Attempt recovery: Try to restore your data from the backup to the simulated environment. This will help you assess the effectiveness of your backup and recovery procedures.
4. Cloud-based backup testing for different recovery scenarios
Restore workstations: If you use cloud backup for your workstations, test restoring your files to a new device. This will show the functionality of the cloud backup service and ensure that your data can be accessed and restored successfully.
Restore server or network data: In addition to endpoints, you’ll also want to restore your servers or networks to different business locations. This lets you pressure test the cost of restores to account for things like hidden fees, and to ensure functions like immutability are properly configured.
5. Regular backup verification
Check file integrity: Regularly verify the integrity of your backup files using checksums or hash functions. This will help detect any corruption or damage that may have occurred.
Review backup logs: Monitor your backup logs for any errors or warnings that might indicate issues with the backup process.
By following these methods, you can ensure that your device backups are reliable and that you can recover your data effectively in case of a disaster.
The human element
Don’t forget that this includes things like establishing where and how you’ll communicate if, for instance, company email is offline. It’s also important to designate incident managers to streamline decision making and ensure that essential personnel have the access and permissions they need.
How cloud storage can help
Store your backup data in readily accessible, hot storage. This minimizes retrieval times during a disaster, enabling faster recovery of critical applications and data.
By implementing a robust backup strategy that incorporates the 3-2-1 backup rule (or, the more robust, and increasingly enterprise standard 3-2-1-1-0 method), immutability, version control, and cloud storage, you can ensure the protection of your critical data against various threats. And, by testing frequently, you can rely on the fact that those backups—and your team—are ready to get your business back online as soon as possible.
If you work with Backblaze B2, you’re probably already aware of resources such as the Backblaze B2 Python SDK and the Backblaze B2 Command Line Tool, but did you know that there is also a Terraform Provider for Backblaze B2, an SDK for Java, and a whole slew of open source samples showing how to integrate with Backblaze B2 from web browsers, serverless platforms, and more? Today, I’ll take you on a quick tour of our open source SDKs, tools, and sample code, pointing out some interesting sights along the way.
https://github.com/backblaze-b2-samples contains unsupported samples and demos showing how to integrate Backblaze B2 with a wide variety of services, frameworks, and applications.
Not every Backblaze B2 operation is accessible via the S3 Compatible API—for example, application key management—so we also support a range of open source SDKs for accessing Backblaze B2’s Native API from a variety of programming languages:
The Backblaze B2 Python SDK: This SDK provides access to the basic operations of the Native API, such as list_buckets() and download_file_by_id(), as well as a powerful Synchronizer class that implements high performance, multi-threaded file copying between Backblaze B2 and local file storage.
The Backblaze B2 Java SDK: Although it doesn’t include anything quite as sophisticated as the Python Synchronizer, the Java SDK does implement high-level functionality such as uploadLargeFile(), which encapsulates all of the mechanics of a multi-threaded file upload in a single method call. We also use it internally at Backblaze in our production environment.
blazer, an open source Backblaze B2 SDK for Go (aka golang): We adopted blazer from its original author, Toby Burress, when he was no longer able to maintain it. We’ve made a few improvements since taking it on, and we’re looking at doing more with it.
The Backblaze GitHub organization also contains a pair of tools built on the Python SDK:
The Terraform Provider for Backblaze B2: This tool allows you to manage Backblaze B2 resources, such as buckets, files, and application keys, from Terraform configurations. Although the provider is written in Go, it embeds the B2 Python SDK for accessing the Backblaze B2 API.
Our https://github.com/backblaze-b2-samples organization contains, at the time of writing, 34 repositories, demonstrating how to use Backblaze B2 in a wide variety of situations. We’ve covered a few of them in past blog posts:
As you explore the https://github.com/backblaze-b2-samples organization, you’ll also find repositories that have not yet been covered here on the Backblaze blog:
B2listen allows you to forward Backblaze B2 Event Notifications to a service listening on a local URL. B2listen uses Cloudflare’s free Quick Tunnels feature to proxy traffic from an internet-accessible URL to a local endpoint.
B2 Browser Upload shows you how to upload files directly to Backblaze B2 from JavaScript code running in the browser, with sample code for both the Backblaze B2 Native and S3-compatible APIs.
The Backblaze B2 Zip Files Example implements a simple Python web app, using the Flask web application framework and the flask-executor task queue, that can compress a set of files located in Backblaze B2 into an archive, also stored in Backblaze B2, without using any local storage.
We’ll write more about these, and other, as yet unreleased, open source projects, over the coming weeks and months, but, if you’d like us to prioritize any of the above three repositories, or any of our other projects, let us know in the comments!
When you think about cloud performance, metrics like latency and throughput are probably the first things that come to mind. We covered those metrics pretty extensively here and here. So, today, I’m walking through some factors that affect cloud performance that may not get talked about as often, including:
These factors may not be “surprising” per se especially if you remember the pain of trying to download The Matrix over dial up. But they are all things that you should consider (and that you have more control over) when thinking about cloud performance overall.
Let’s dig in.
1. The size of your files
This one is pretty obvious. Larger files take longer because they require more data to be transferred. If you have a 10Mbps upload connection, a 1GB file will take approximately 800 seconds (13 minutes and 20 seconds) to upload, whereas a 100MB file will take about 80 seconds (a minute and 20 seconds). Most enterprise-grade internet connections offer higher upload speeds, but 10Mbps makes the math approachable for the sake of argument.
Small files—that is, those less than 5GB—can be uploaded in a single API call. (Note: this can vary based on cloud storage provider and configuration.) Larger files up to 10TB can be uploaded as “parts” in multiple API calls. Each part has to be a minimum of 5MB and a maximum of 5GB.
You’ll notice that there is quite an overlap here! For uploading files between 5MB and 5GB, is it better to upload them in a single API call, or split them into parts? What is the optimum part size? For backup applications, which typically split all data into equally sized blocks, storing each block as a file, what is the optimum block size? As with many questions, the answer is: it depends.
2. The number of parts you upload or download
Each API call incurs a more-or-less fixed overhead due to latency. For a 1GB file, assuming a single thread of execution, uploading all 1GB in a single API call will be faster than 10 API calls each uploading a 100MB part, since those additional nine API calls each incur some latency overhead. So, bigger is better, right?
3. Block (part) size
Not necessarily, and that brings us to part size. Multi-threading, as mentioned above, affords us the opportunity to upload multiple parts simultaneously, which improves performance—but there are trade-offs. Typically, each part must be stored in memory as it is uploaded, so more threads means more memory consumption. If the number of threads multiplied by the part size exceeds available memory, then either the application will fail with an out of memory error, or data will be swapped to disk, reducing performance.
Downloading data offers even more flexibility, since applications can specify anyportion of the file to download in each API call. Whether uploading or downloading, there is a maximum number of threads that will drive throughput to consume all of the available bandwidth. Exceeding this maximum will consume more memory, but provide no performance benefit.
So, what to do to get the best performance possible for your use case?
Simple: Customize your settings
Most backup and file transfer tools allow you to configure the number of threads and the amount of data to be transferred per API call, whether that’s block size or part size. If you are writing your own application, you should allow for these parameters to be configured. When it comes to deployment, some experimentation may be required to achieve maximum throughput given available memory.
The big takeaway: When it comes to cloud performance, the metrics you need to care about and the performance you actually need are highly dependent on your use case, your own infrastructure, your workload, and all the network connections between your infrastructure and the cloud provider as well. So, when you’re deciding how to store and use your data, it’s worth taking some extra time to consider the above factors for optimum performance.
This post has been updated since it was originally published.
With spending on public cloud services expected to double by 2028, many businesses are looking for ways to cut cloud costs—or at least gain predictability in their spend. Forecasting cloud storage costs should be straightforward once you know what to look for.
Here are five tips you can use when doing your due diligence on the cloud storage vendors you are considering. The goal is to create a cloud storage forecast that you can rely on each and every month.
Tip 1: Navigate tiered pricing structures carefully
Many cloud providers still use tiered pricing structures, which can be misleading if not carefully understood. For example:
AWS S3 Storage Pricing Example
For this post, we’re comparing with hypothetical data stored in AWS S3’s U.S. East Region (N. Virginia) using pricing available at the time of publishing. Note that many factors may affect your final price, including selecting a different region, choosing a different storage tier, etc.
First 50 TB/month = $0.023 per GB
Next 450 TB/month = $0.022 per GB
Over 500 TB/month = $0.021 per GB
In order to receive lower pricing, you have to reach a specific amount of data stored. But, the lower rate only applies to data above the threshold for that tier. In other words, you don’t get a discount on the cumulative amount—each pricing tier is reflected in the data you’re storing.
The mistake sometimes made is estimating your entire storage cost based on the level for the total data stored. For example, if you had 600TB of storage, you could wrongly calculate as follows:
600,000GB x $0.021 = $12,600/month
When, in fact, you should do the following:
(50,000GB x $0.023) + (450,000GB x $0.022) + (100,000GB x $0.021) = $13,150/month
That was just for storage. Make sure you consider the tiered pricing tables for data retrieval, and API transactions as well.
Tip 2: Don’t choose the wrong storage class
Many cloud providers, especially hyperscalers, now offer a wider array of storage classes than ever before. The idea is that you can trade service capabilities for lower costs. If you don’t need immediate access to your files or don’t want data replication or 11 nines of durability, you can choose to downgrade your service and gain cost savings. The biggest problem with this method is that you have to know what you are going to do with your data to pick the right service—as well as correctly anticipate future business needs—because mistakes can get very expensive. For example:
You choose a low cost, cold storage tier that takes hours or days to restore your data. What can go wrong? You need some files back immediately (if, for example, your backups are corrupted by ransomware) and you end up paying 10-20 times the cost to expedite your restore.
You choose one storage class and decide you want to upload some data to a compute-based application or to another region—features not part of your current service. The good news? You can usually move the data. The bad news? Even if you’re transferring within the same cloud storage company’s infrastructure, you’re often charged a transfer fee to move the data because you didn’t choose the right storage class when you started. These fees often eradicate any “savings” you had gotten from the lower priced tier.
Basically, if your needs change as they pertain to the data you have stored, you will pay more than you expect to get your data where you need it to be.
Tip 3: Don’t pay for deleted (or modified) files
Some cloud storage companies have a minimum amount of time you are charged for storage for each file uploaded. Typically this minimum period is between 30 and 90 days. You are charged even if you delete the file before the minimum period. For example (assuming a 90 day minimum period), if you upload a file today and delete the file tomorrow, you still have to pay for storing that deleted file for the next 88 days.
This “feature” often extends to files deleted due to versioning. If you set your system to keep three versions of each file, with older versions automatically deleted, you end up paying for those deleted versions for the full minimum duration.
In a typical backup workflow, let’s say you are using a cloud storage service to store your files and your backup program is set to a 30 day retention. That means you will be perpetually paying for an additional 60 days worth of storage (for files that were pruned at 30 days). In other words, you would be paying for a 90 day retention period even though you only have 30 days worth of backups.
Tip 4: Beware of hidden minimums
As the cloud storage market has matured, pricing models have become more complicated. To create an accurate budget, it’s crucial to understand all potential cost components, including some that might not be immediately obvious. Here are two key areas to examine:
Minimum monthly charges: Some providers charge a set fee regardless of how little you store. For instance, you might pay for 1TB even if you only use 100GB.
Minimum file sizes: Some services round up small files to a minimum billable size, often 128KB. While this might seem insignificant, it can add up quickly if you have millions of small files.
Tip 5: Be suspicious of the fine print
Misdirection is the art of getting you to focus on one thing so you don’t focus on other things going on. Practiced by magicians and some cloud storage companies, the idea is to get you to focus on certain features and capabilities without delving below the surface into the fine print. (And, sometimes the prices this technique generates feels like someone has pulled a rabbit out of a hat—to your company’s detriment.)
Read the fine print and as you scroll through the multi-page pricing tables and linked pages of all of the rules that shape how you can use a given cloud storage service. Stop and ask, “What are they trying to hide?” If you find phrases like: “We reserve the right to limit your egress traffic,” or “New users get free usage tier for 12 months,” or “Provisioned requests should be used when you need a guarantee that your retrieval capacity will be available when you need it,” take heed.
And, even if it seems like you can turn the tables and use things like free credits in the short term, remember that you’ll want to have a plan for your long-term infrastructure when those credits run out as well.
How to build a predictable cloud storage budget
As organizations increasingly rely on cloud storage for everything from day-to-day operations to long-term data archiving, the ability to accurately forecast and control these costs can significantly impact overall IT budgets and business planning.
The first place to start is data storage as it’s generally the easiest for a company to calculate. For a given month, you can calculate your data volume as follows:
Data stored = current data + new data – deleted data
Take that total and multiple by the monthly storage rate and you’ll get your monthly storage costs.
Things can get more complicated if your business regularly uploads and downloads data. The data stored at the end of the month should get you at least in the ballpark. But, creating a predictable cloud storage budget requires a holistic understanding of your data needs, usage patterns, and the pricing structures of your chosen provider. It’s not just about estimating how much data you’ll store, but also how you’ll interact with that data over time. Will you be frequently accessing and modifying files, or primarily using the storage for long-term archiving? Are there seasonal fluctuations in your data storage or retrieval patterns? These factors can all influence your overall costs, and we’ll walk through a scenario to show that next.
Let’s do the math
To illustrate how to calculate your cloud storage costs, let’s work through an example using current Backblaze B2 pricing. We’ll focus on a single month for a growing business that is backing up business data to the cloud and verifying their backups have zero errors during recovery:
Initial storage at the beginning of the month: 100TB
New data added during the month: 10TB
Data deleted during the month: 5TB
Downloads during the month (egress): 75TB
Backblaze has built a cloud storage calculator that computes costs for all of the major cloud storage providers. Using this calculator, we find that Amazon S3 would cost $2,675 to store this data for a month, while Backblaze B2 would charge just $630.
Using those numbers for storage and assuming you download 75TB a month for backup validation testing, you get a total monthly cost of $8,725 for Amazon S3; Backblaze B2 would be $630 a month.
The additional cost you see from AWS S3 is from download costs, also known as egress fees, and they can certainly take a toll on your budget. Backblaze offers free egress up to three times the amount you have stored so you can move data when and where you prefer.
The chart below provides the breakdown of the expected cost.
Backblaze B2
Amazon S3
Storage
$630
$2,675
Egress
Free*
$6,050
Totals:
$630
$8,725
*Up to 3x of average monthly data stored, then $0.01/GB for additional egress.
Of course each month you will add and delete storage, so you’ll have to account for that in your forecast. And, as we mentioned above, there may also be other fees like minimum storage duration fees or API transaction fees. Using the cloud storage calculator noted above, you can get a reasonable estimate of your total cost over the budget forecasting period.
Finally, you can use the Backblaze B2 storage calculator to address potential use cases that are outside of your normal operations, such as if you delete a large project from your storage or you need to download a large amount of data. Running the calculator for these types of actions lets you obtain a solid estimate for their effect on your budget before they happen and lets you plan accordingly.
Understanding cloud storage pricing gives you options
Creating a predictable cloud storage forecast is key to taking full advantage of all of the value in cloud storage. Organizations like Austin City Limits, Amplify, and Runbiz were able to move to the cloud because they could reliably predict their cloud storage cost with Backblaze B2. You don’t have to let pricing tiers, hidden costs, and fine print stop you. Backblaze makes predicting your cloud storage costs easy.
Every day, thousands of Backblaze customers create and update files. These changes make their way into our system to be securely stored. Sometimes they are sent to us immediately, while other times the differentials are batched up into a job that runs at a scheduled time.
In this post, I’m sampling three points in our network where we take in a lot of ingress traffic off of the internet, and we’re going to explore some of the trends that we see.
Reading the ingress tea leaves
So, why do we care about ingress trends? In short, it helps us with capacity planning, and it also tells us a lot about how people use cloud storage. We often think of planning in longer terms—weeks, months, or years. Here I wanted to focus on some of the patterns that we see during a shorter period; for example, a single day or a significant date, like the end of the calendar month. There are some interesting patterns we see in our client behavior that keep us on our toes when we are performing capacity planning.
We currently have two product offerings that have different usage and traffic patterns:
Backblaze B2 Cloud Storage: Ingress and egress, high variance in traffic levels throughout the day, hour, and at the start of month.
Backblaze Computer Backup: Heavy ingress, with a small variance in traffic levels during the business day or weekday vs. weekend.
Since humans are using our system, we see very human quirks in our traffic profiles. For example, we humans like round numbers! We notice that a lot of backup jobs kick off at midnight local or UTC, or fire off at the top of the hour, or trigger on the first of the month. This means we see spikes of network traffic during these periods. Additionally, a lot of new content gets created during the day and then queued up to be uploaded to us in an overnight backup job.
Scope and terms
Today we’re going to look at ingress traffic, which means we’re monitoring uploads from both Backblaze Computer Backup and Backblaze B2 into our environment. We’ll save downloads, traffic coming out of Backblaze, for analysis in future posts.
One common term that you’ll see on our graphs in the 95th percentile. The 95th percentile number is a point where 95% of all measurements are under and only 5% are over. This is a very typical method to use for monitoring, billing, and trend analysis in the telecom industry. It maps to a standard bell curve, and tells you that you’re capturing the vast majority of usage for planning purposes.
In one of our monitoring systems, we are sampling and recording the utilization on our network links and computing a 95th percentile over a five minute period.
With these items defined, let’s get into the data with some charts!
Sample 1: One-month trend
In this first sample, we see that the majority of our daily traffic falls within a nice range. What stands out here is the clock tick over from February to March, where we see a spike of ingress traffic that is outside the expected daily range.
Taking that same dataset, let’s take a closer look at the end of the month and zoom in on the calendar change into March.
Adding a vertical red line on 00:00 UTC where the month changes over, we see that there must be a lot of automated jobs that kick in right at the clock changeover into the new month.
Sample 2: Top of the hour
Taking a look at another traffic sample from another point in our network, we see very distinct traffic patterns on the top of almost every hour.
Sample 3: Pacific Time Zone working hours
Here’s a sample of traffic in our US-West region. During the business day on the West Coast, we see a lull in traffic, with a pickup after the business day is done. This makes sense to us as there are jobs that backup daily content that start to send traffic to us overnight.
What does this mean for you?
It’s very interesting to see the impact of humans in our network traffic and the patterns that emerge. Generally we humans create and modify things during the day, and we like to back them up over night for safekeeping. And we also like round numbers—people tend to send data at the top of the hour, midnight, or end of the month.
All of these elements are very important in how we, at Backblaze, capacity plan and balance traffic over transit links. We do a lot of work to make sure that no matter what time of day or day of the month, you can reliably get your data into Backblaze.
But, you might also look at this data and take away a meaningful conclusion: Much like choosing to go to the grocery store at 10:30 a.m. on a Tuesday versus fighting the after-work rush at 6:00 p.m., scheduling jobs on the 15, 30, or 45 minute mark or mid-month instead of at the end of the month would mean you’re up against less traffic, which is never a bad thing (and it also smooths out our ingress, which we wouldn’t be mad about either).
At the end of the day, however you choose to schedule your jobs works for us. We’re just glad we’re able to store and protect our customers’ data reliably and affordably, and we’re happy to pass along any tips and trips for a better, less congested, backup experience as well.
Thanks for reading, and stay tuned for more graphs and commentary on how we strive to build a reliable, scalable, and forward looking network to serve our customer’s needs.
The tools you use impact your efficiency, productivity, and the quality of your work. That’s true whether you’re a carpenter looking for the best saw blades, a chef choosing high-quality knives, or a developer or programmer investing in top-notch software. The B2 Command Line Interface (CLI) is one tool that you can use to interact with B2 Cloud Storage, and some recent improvements make it a more powerful, intuitive part of your arsenal.
It’s been a while since our last blog about the Backblaze B2 Command Line Tool (B2 CLI for short). Today, we’re sharing more details on the key enhancements and new features as part of the B2 CLI version 4.1.0.
Let’s dive into the highlights of these changes and explore how they can elevate your B2 CLI experience.
User experience enhancements
1. A new nested command structure
Gone are the days of sifting through a long list of commands to find what you need. The B2 command structure has been revamped to be more intuitive and organized. With the new nested command structure, related commands are logically grouped together. The new structure looks like b2 <resource>. It makes it easier for you to locate and utilize the functionality you require. Whether you’re managing files, buckets, keys, or accounts, commands are now categorized in a way that aligns with their functions. This gives you a clearer and more concise enhanced user experience.
New command structure.
2. Streamlined ls and rm commands
Why use two when one will do? The b2 ls and b2 rm commands can now accept a single cohesive string, B2 URI (e.g., b2://bucketName/path), instead of two separate positional arguments, giving you enhanced consistency and usability. It simplifies the command syntax and reduces potential for errors by eliminating the chance of misplacing or mistyping one of the separate arguments. And it ensures that the bucket and file path are always correctly associated with each other. This change minimizes confusion and helps to avoid common mistakes that can occur with multiple arguments.
In addition, some commands, such as b2 file large parts, accept a B2 ID URI (e.g. b2id://4_zf1f51fb…), which specifies a file by its unique identifier (a.k.a. Fguid).
Some redundant commands have also been deprecated with the introduction of the B2 and B2 URIs. For example: download-file-by-id and download-file-by-name functionality is available through b2 file download b2://bucketname/path and b2 file download b2id://fileid command.
3. Enhanced credential management
To enhance security and performance, the CLI will no longer persist credentials on disk if they are passed through B2_* environment variables (that is, B2_application_key_id and B2_application_key). This reduces the risk of unauthorized access to your credentials and improves the overall security of your environment.
At the same time, it’s important that security is balanced with performance. To address this, you can persist your credentials to local cache and can continue using local cache for better performance. You can explicitly choose to persist your credentials by using the b2 account authorize command.
By eliminating the automatic persistence of credentials from environment variables and providing a clear method to manage local caching, you now have a balanced approach that keeps your data secure while ensuring efficient CLI operations.
4. Transition to kebab-case flags
Previously CLI flags had mixed camelCase and kebab-case styles. Users needed to remember the style to use it along with the name for the option. But kebab-case, where words are separated by hyphens (e.g., --my-flag), offers a clearer and more straightforward way to read and interpret flags. We’ve transitioned all CLI flags to --kebab-case. This style not only enhances readability, making it easier to understand complex commands at a glance, but also makes it easy to remember. It’s particularly beneficial when flags are composed of multiple words, as it reduces visual clutter and makes the flag names more accessible.
5. Simplified listing with ls
Ever wondered how to list all your buckets in one go? Now, you can call b2 ls without any arguments to do this. Whether you’re managing multiple buckets or just need a quick overview of your entire bucket inventory, the ability to list all buckets with a single command saves you time and effort. The enhancement to the b2 ls command is all about making your life easier. (As an aside, it’s also the quickest way to check that Backblaze B2 is correctly configured and you’re using the right set of credentials.)
6. Handy aliases for common flags
Why go the long way when you can take shortcuts? You can now use -r as an alias for the --recursive argument and -q for the --quiet argument. These shortcuts make your command-line interactions quicker and more efficient. You can get things done with fewer presses.
7. Global quiet mode
The --quiet option is now available for all commands, allowing you to suppress all messages printed to stdout and stderr. This is particularly useful for scripting and automation, where you want to minimize output.
8. Autocomplete
This enhancement for the B2 CLI means that you no longer have to remember and type out lengthy command arguments or options manually. As you start typing a command, the CLI will provide you with suggestions for completing the command, options, and arguments based on the context of your input. This can significantly save up your time and help you avoid typos or incorrect entries.
New features to boost your productivity
In addition to the CLI enhancements, we’ve also recently announced a few new features and capabilities for Backblaze B2, including:
Event Notifications: Event Notifications helps you automate workflows and integrate Backblaze B2 with other tools and systems. You can now manage Event Notification rules through b2 bucket notification-rule commands directly from the CLI. The feature is available in public preview. If you’re interested, check out the announcement and sign up here.
Unhide files with ease: Previously, if you needed to reverse the hiding of a file, the process could be cumbersome or require multiple steps. To restore hidden files, using the b2 file unhide command is now as simple as it sounds. You only need to specify the file you want to unhide, and the command will handle the rest. This ensures that you can quickly and accurately restore file visibility without unnecessary complications. Whether you’ve hidden previous backup files and need to access them again, or when reorganizing your storage or adjusting file visibility for different users, or if you unintentionally hide files and need to make them visible for auditing or review purposes, you can use this command swiftly.
Custom file upload timestamps: You can now enable custom file upload timestamps on your account, enabling you to preserve original upload times for your files. This feature is ideal for maintaining accurate records for compliance and reporting, and it gives you greater control over the file metadata. If you’d like to enable the feature, please reach out to Backblaze Support.
In addition to the above highlights, we’ve implemented crucial fixes to improve the stability and reliability of the CLI. We’ve also made several improvements to our documentation, ensuring you have the guidance you need right at your fingertips.
Start using the new features today
The easier we can make your CLI experience, the easier your job becomes and the more you can get out of Backblaze B2. Install or upgrade the B2 CLI today to take advantage of all the new features.
As always, we value your feedback. If you have any thoughts or experiences to share as you start using the new enhancements and features, please let us know in the comments or submit feedback via our Product Portal. Your input is crucial in helping us continue to improve and innovate.
Last month, Backblaze Principal Storage Cloud Storyteller, Andy Klein, and I presented a webinar, Leveraging your Cloud Storage Data in AI/ML Apps and Services, in which we explored the various ways AI/ML applications use and store data. In addition to sharing insights from our customers who leverage Backblaze B2 Cloud Object Storage for their AI/ML needs, we also demonstrated a simple AI use case: a retrieval-augmented generation (RAG) chatbot answering questions based on custom context downloaded from a private Backblaze B2 Bucket. After the webinar, I posted the demo source code to a GitHub repository: https://github.com/backblaze-b2-samples/ai-rag-examples.
In this blog post, I’ll recap a little of the webinar, and explain how you can use the demo source code as a basis for your own experiments with RAG and large language models (LLMs).
But why, Pat?
You might be asking yourself, why build a chatbot when multiple online services, such as ChatGPT, are just a click away? It’s a good question. The main motivation is privacy. Suppose you want your chatbot to use confidential data in generating its responses. By running an LLM on your own machine, whether on-premises or on a virtual machine (VM) under your control in a public cloud provider’s infrastructure, you eliminate the risks of that data surfacing in response to a question from a user outside your organization.
In the webinar, I showed two Python apps running on a GPU-equipped VM at Vultr, one of Backblaze’s compute partners. The first app used the GPT4All Python SDK to create a very simple conversational chatbot running a local instance of a large language model (LLM), which it used in answering general questions. Here’s an example from the webinar:
Ask me a question: What were the causes of the First World War? The causes of the First World War are complex and varied, but some key factors include nationalism, imperialism, militarism, alliances between nations, and the assassination of Archduke Franz Ferdinand. Nationalism led to tensions between ethnic groups and their respective governments, while imperialism saw countries competing for territories and resources around the world. Militarism also played a role as many European powers built up large armies and navies in preparation for potential conflicts. The complex web of alliances between nations meant that any conflict could quickly escalate into a latIer war, and the assassination of Archduke Franz Ferdinand by a Serbian nationalist was the spark that ignited the powder keg of tensions already present in Europe at the time.
Now, I’m not a history scholar, but that looks like a pretty good answer to me! (History scholars, you are welcome to correct me.)
The second app used the Langchain framework to implement a more elaborate chatbot, again running on my own machine at Vultr, that used PDF data downloaded from a private bucket in Backblaze B2 as context for answering questions. As much as I love our webinar attendees, I didn’t want to share genuinely confidential data with them, so I used our Backblaze B2 Cloud Storage documentation as context. The chatbot was configured to use that context, and only that context, in answering questions. From the webinar:
Ask me a question about Backblaze 82: What's the difference between the master application key and a standard application key?
The master application key provides complete access to your account with all capabilities, access to all buckets, and has no file prefix restrictions or expiration. On the other hand, a standard application key is limited to the level of access that a user needs and can be specific to a bucket.
Ask me a question about Backblaze B2: What were the causes of the First World War?
The exact cause of the First World War is not mentioned in these documents.
The chatbot provides a comprehensive, accurate answer to the question on Backblaze application keys, but doesn’t answer the question on the causes of the First World War, since it was configured to use only the supplied context in generating its response.
During the webinar’s question-and-answer session, an attendee posed an excellent question: “Can you ask [the chatbot] follow-up questions where it can use previous discussions to build a proper answer based on content?” I responded, “Yes, absolutely; I’ll extend the demo to do exactly that before I post it to GitHub.” What follows are instructions for building a simple RAG chatbot, and then extending it to include message history.
Building a simple RAG chatbot
After the webinar, I rewrote both demo apps as Jupyter notebooks, which allowed me to add commentary to the code. I’ll provide you with edited highlights here, but you can find all of the details in the RAG demo notebook.
The first section of the notebook focuses on downloading PDF data from the private Backblaze B2 Bucket into a vector database, a storage mechanism particularly well suited for use with RAG. This process involves retrieving each PDF, splitting it into uniformly sized segments, and loading the segments into the database. The database stores each segment as a vector with many dimensions—we’re talking hundreds, or even thousands. The vector database can then vectorize a new piece of text—say a question from a user—and very quickly retrieve a list of matching segments.
Since this process can take significant time—about four minutes on my MacBook Pro M1 for the 225 PDF files I used, totaling 58MB of data—the notebook also shows you how to archive the resulting vector data to Backblaze B2 for safekeeping and retrieve it when running the chatbot later.
The vector database provides a “retriever” interface that takes a string as input, performs a similarity search on the vectors in the database, and outputs a list of matching documents. Given the vector database, it’s easy to obtain its retriever:
retriever = vectorstore.as_retriever()
The prompt template I used in the webinar provides the basic instructions for the LLM: use this context to answer the user’s question, and don’t go making things up!
prompt_template = """Use the following pieces of context to answer the question at the end.
    If you don't know the answer, just say that you don't know, don't try to make up an answer.

    {context}

    Question: {question}
    Helpful Answer:"""

prompt = PromptTemplate(
    template=prompt_template, input_variables=["context", "question"]
)
The RAG demo app creates a local instance of an LLM, using GPT4All with Nous Hermes 2 Mistral DPO, a fast chat-based model. Here’s an abbreviated version of the code:
model = GPT4All(
    model='Nous-Hermes-2-Mistral-7B-DPO.Q4_0.gguf',
    max_tokens=4096,
    device='gpu'
)
LangChain, as its name suggests, allows you to combine these components into a chain that can accept the user’s question and generate a response.
As mentioned above, the retriever takes the user’s question as input and returns a list of matching documents. The user’s question is also passed through the first step, and, in the second step, the prompt template combines the context with the user’s question to form the input to the LLM. If we were to peek inside the chain as it was processing the question about application keys, the prompt’s output would look something like this:
Use the following pieces of context to answer the question at the end. If you don't know the answer, just say that you don't know, don't try to make up an answer.

<Text of first matching document>

<Text of second matching document>

Question: What's the difference between the master application key and a standard application key?

Helpful Answer:
This is the basis of RAG: building an LLM prompt that contains the information required to generate an answer, then using the LLM to distill that prompt into an answer. The final step of the chain transforms the data structure emitted by the LLM into a simple string for display.
Now that we have a chain, we can ask it a question. Again, abbreviated from the sample code:
question = 'What is the difference between the master application key and a standard application key?'
answer = chain.invoke(question)
Adding message history to the simple RAG chatbot
The first step of extending the chatbot is to give the LLM new instructions, similar to its previous prompt template, but including the message history:
prompt_template = """Use the following pieces of context and the message history to answer the question at the end. If you don't know the answer, just say that you don't know, don't try to make up an answer.

Context: {context}

History: {history}

Question: {question}

Helpful Answer:"""

prompt = PromptTemplate(
    template=prompt_template, input_variables=["context", "question", "history"]
)
The chain must be modified slightly to accommodate the message history:
Now, we define a very simple in-memory message store that uses a session_id parameter to manage multiple simultaneous conversations:
store = {}

def get_session_history(session_id: str) -> BaseChatMessageHistory:
    if session_id not in store:
        store[session_id] = InMemoryChatMessageHistory()
    return store[session_id]
LangChain provides a wrapper, RunnableWithMessageHistory, that combines the message store with the above chain to create a new chain with message history capability:
Now we can feed a series of related questions into the new chain:
questions = [
    'What is the difference between the master application key and a standard application key?',
    'Which one would I use to work with a single bucket?',
    'Can you tell me anything more about this topic?'
]

for question in questions:
    print(f'\n{question}\n')
    answer = with_message_history.invoke(
        {"question": question},
        config={"configurable": {"session_id": "abc123"}},
    )
    print(f'{answer}\n')
I have to admit, I was pleasantly surprised by the results:
What is the difference between the master application key and a standard application key?
A master application key grants broad access privileges, while a standard application key is limited to the level of access that a user needs.
Which one would I use to work with a single bucket?
You would use a standard application key to work with a single bucket as it has limited access and only grants permissions needed for specific tasks, unlike the master application key which provides broad access privileges.
Can you tell me anything more about this topic?
Sure! The master application key is typically used by developers during development or testing phases to grant full access to all resources in a Backblaze B2 account, while the standard application key provides limited permissions and should be used for production environments where security is paramount.
Processing this series of questions on my MacBook Pro M1 with no GPU-acceleration took three minutes and 25 seconds, and just 52 seconds with its 16-core GPU. For comparison, I spun up a VM at Ori, another Backblaze partner offering GPU VM instances, with an Nvidia L4 Tensor Core GPU and 24GB of VRAM. The only code change required was to set the LLM device to ‘cuda’ to select the Nvidia GPU. The Ori VM answered those same questions in just 18 seconds.
The Nvidia L4 Tensor Core GPU: not much to look at, but crazy-fast AI inference!
Go forth and experiment
One of the reasons I refactored the demo apps was that notebooks allow an interactive, experimental approach. You can run the code in a cell, make a change, then re-run it to see the outcome. The RAG demo repository includes instructions for running the notebooks, and both the GPT4All and LangChain SDKs can run LLMs on machines with or without a GPU. Use the code as a starting point for your own exploration of AI, and let us know how you get on in the comments!
As of the end of Q2 2024, Backblaze was monitoring 288,665 hard drives (HDDs) and solid state drives (SSDs) in our cloud storage servers located in our data centers around the world. We removed from this analysis 3,789 boot drives, consisting of 2,923 SSDs and 866 hard drives. This leaves us with 284,876 hard drives under management to review for this report. We’ll review the annualized failure rates (AFRs) for Q2 2024 and the lifetime AFRs of the qualifying drive models, and we’ll also check out drive age versus failure rates over time. Along the way, we’ll share our observations and insights on the data presented and, as always, we look forward to you doing the same in the comments section at the end of the post.
Hard drive failure rates for Q2 2024
For our Q2 2024 quarterly analysis, we remove from consideration: drive models which did have at least 100 drives in service at the end of the quarter, drive models which did not accumulate 10,000 or more drive days during the quarter, and individual drives which exceeded their manufacturer’s temperature specification during their lifetime. The removed pool totalled 490 drives, leaving us with 284,386 drives grouped into 29 drive models for our Q2 2024 analysis.
The table below lists the AFRs and related data for these drive models. The table is sorted large to small by drive size then by AFR within drive size.
Notes and observations on the Q2 2024 Drive Stats
Upward AFR: The AFR for Q2 2024 was 1.71%. That’s up from Q1 2024 at 1.41%, but down from one year ago (Q2 2023) at 2.28%. While the quarter over quarter increase was a bit surprising, quarterly fluctuations in AFR are expected. Sixteen drive models had an AFR of 1.71% or below while 13 drive models had an AFR above.
Two good zeroes: In Q2 2024, two drive models had zero failures, a 14TB Seagate (model: ST14000NM000J) and a 16TB Seagate (model: ST16000NM002J). Both have a relatively small number of drives and drive days for the quarter, so their success is somewhat muted, but the 16TB Seagate drive model has a very respectable 0.57% lifetime failure rate.
Another GOAT is gone: In Q1, we migrated the last of our 4TB Toshiba drives. In Q2, we migrated the last of our 6TB drives, including all of the Seagate 6TB drives which had reached an average age of nine years (108 months). This Seagate drive model closed out its career at Backblaze with an impressive 0.86% lifetime AFR.
Currently the 4TB Seagate (model: ST4000DM000) is our oldest data drive model in production at an average age of 99.5 months. The data on these drives is scheduled to be migrated over the next quarter or two using CVT, our in-house drive migration system. They’ll never reach nine years of service.
The 10-Year Club: With the 6TB Seagate drives being migrated as they hit 10 years of service, we wondered: What is the oldest data drive in service? The answer, a 4TB HGST drive (model: HMS5C4040ALE640) with 9 years, 11 months and 23 days service as of the end of Q2. Alas, the Backblaze Vault in which this drive resides is now being migrated as are many other drives with over nine years of service. We’ll see next quarter to see if any of them made it to the 10-Year Club before they are retired.
While there are no data drives with 10 years of service, there are 11 HDD boot drives that exceed the mark. In fact one, a 500GB WD drive (model: WD5000BPKT) has over 11 years of service. (Psst, don’t tell the CVT team.)
An HGST surprise: Over the years, the HGST drive models we have used performed very well. So, when the 12TB HGST (model: HUH721212ALN604) drive showed up with a 7.17% AFR for Q2, it’s news. Such uncharacteristic quarterly failure rates for this model actually go back about a year, although the 7.17% AFR is the largest quarterly value to date. As a result, the lifetime AFR has risen from 0.99% to 1.57% over the last year. While the lifetime AFR is not alarming, we are paying attention to this trend.
Lifetime hard drive failure rates
As of the end of Q2 2024, we were tracking 284,876 operational hard drives. To be considered for the lifetime review, a drive model was required to have 500 or more drives as of the end of Q2 2024 and have over 100,000 accumulated drive days during their lifetime. When we removed those drive models which did not meet the lifetime criteria, we had 283,065 drives grouped into 25 models remaining for analysis as shown in the table below.
Age, AFR, and snakes
One of the truisms in our business is that different drive models fail at different rates. Our goal is to develop a failure profile for a given drive model over time. Such a profile can help optimize our drive replacement and migration strategies, and ultimately maintains the durability of our cloud storage service.
For our cohort of data drives, we’ll look at the changes in the lifetime AFR over time for drive models with at least one million drive days as of the end of Q2 2024. This gives us 23 drive models to review. We’ll divide the drive models into two groups: those whose average age is five years (60 months) or less, and those whose average age is above 60 months. Why that cutoff? That’s the typical warranty period for enterprise class hard drives.
Let’s start by plotting the current lifetime AFR for the 14 drives models that have an average age of 60 months or less as shown in the chart below.
Let’s review the drive models by characterizing the four quadrants as follows:
Quadrant I: Drive models in this quadrant are performing well, and have a respectable AFR of less than 1.5%. Drive models to the right in this quadrant might require a little more attention over the coming months than those to the left.
Quadrant II: These drive models have failure rates above 1.5%, but are still reasonable at around 2% lifetime AFR. What is important is that AFR does not increase significantly over time.
Quadrant III: There are no drives currently in this quadrant, but if there were it would not be a cause for alarm. Why? Some drive models experience higher rates of failure early on, and then following the bathtub curve, their AFR drops as they get older.
Quadrant IV: These drive models are just starting out and are just beginning to establish their failure profile, which at the moment is good.
At a glance, the chart tells us that everything seems fine. The drives in Quadrant I are performing well, the two drives in Quadrant II could be better, but are still acceptable, and there are no surprises in the newer drive models to this point. Let’s see how things fair for the drive models which have an average age of over 60 months as in the chart below.
There are nine drive models which fit the average age criteria, including the Seagate 6TB drive (in yellow) whose drives were removed from service in Q2. As you can see the drive models are spread out across all four quadrants. As before, Quadrant I contains good drives, Quadrants II and III are drives we need to worry about, and Quadrant IV models look good so far.
If we were to stop here we could decide for example that the 4TB Seagate drives are first in line for the CVT migration process, but not so fast. All of these drive models have been around for at least five years and we have their failure rates over time. So, rather than rely on just a point in time, let’s look at their change in failure rates over time in the chart below.
The snake chart, as we’re calling it, shows the lifetime failure rate of each drive model over time. We started at 24 months to make the chart less messy. Regardless, the drive models sort themselves out into either Quadrant I or II once their average age passes 60 months. Let’s take a look at the drives in each of those quadrants.
Quadrant I: Five of the nine drive models are in Quadrant I as of Q2 2024. The two 4TB HGST drives (brown and purple lines) as well as the 6TB Seagate (red line) have nearly vertical lines indicating their failure rates have been consistent over time, especially after 60 months of service. Such demonstrated consistency over time is a failure profile we like to see.
The failure profile of the 8TB Seagate (blue line) and the 8TB HGST (gray line) are less consistent, with each increasing their failure rates as they have aged. In the case of the HGST drive, the lifetime AFR rose from about 0.5% to 1.0% over an 18 month period starting at 48 months before leveling out. The Seagate drive took about two years starting at 60 months to go from 1.0% to nearly 1.5% before leveling out.
Quadrant II: The remaining 4 drive models ended in this quadrant. Three of the models, the 8TB Seagate (yellow line), the 10TB Seagate (green line), and the 12TB HGST (teal line) have similar failure profiles. All three got to some point in their lifetime and their curve began bending to the right. In other words, their failure rates over time accelerated. While the 8TB Seagate (yellow) shows some signs of leveling off, all three models will be closely watched and replaced if this trend continues.
Also in Quadrant II is the 4TB Seagate drive (black line). This drive model is aggressively being migrated and is being replaced by 16TB and larger drives via the CVT process. As such, it is hard to tell if the nearly vertical failure profile is a function of the replacement process or the drive model failure rate leveling out over time. Either way, the migration of this drive model is expected to be complete in the next quarter or two.
A normal failure profile
If we had to pick one of the drive models to represent a normal failure profile, it would be the 8TB Seagate (blue line, model: ST800DM002). Why? The failure rate for the first 60 months was consistently around 1.0%, Seagate’s predicted AFR. After 60 months, the AFR increased as the drive aged as one would expect. You might have thought we’d choose the failure profile of one of the two 4TB HGST drive models (brown and purple lines). The “trouble” is their failure rates are well below any published AFR by any drive manufacturer. While that’s great for us, their annualized failure rates over time are sadly not normal.
Can AI help?
The idea of using AI/ML techniques to predict drive failure has been around for several years, but as a first step let’s see if predicting drive failure is even an AI-worthy problem. We recently conducted a webinar “Leveraging Your Cloud Storage Data in AL/ML Apps and Services” in which we outlined general criteria to be used in evaluating if AI/ML is needed to solve a given problem, in this case predicting drive failure. The most salient criteria which applies here is that AI is best used for a problem for which you can not consistently apply a set of rules to solve the problem.
A model is trained by taking the source data and applying an algorithm to iteratively combine and weigh multiple factors. The output is a model which can be used to answer questions about the model’s subject matter, in this case drive failure. For example, we train a model using the Drive Stats data for a given drive model for the last year. Then, we ask the model a question using drive Z’s daily SMART stats and related information. We use this data as input to the model, and while there is no exact match, the model will use inference to develop a response of the probability of drive failure for drive Z over time. As such, it would seem that drive failure prediction would be a good candidate for using AI.
What’s not clear is whether what is learned about one drive model can be applied to another drive model. One look at the snake chart above visualizes the issue as the failure profile for each drive model is different, sometimes radically different. For example, do you think you could train a model on the 4TB Seagate drives (black line) and use it to predict drive failures for either of the 4TB HGST drive models (purple and brown lines)? The answer may be yes, but it certainly doesn’t seem likely.
All that said, several research papers and studies have been published over the years attempting to determine whether or not AI/ML can be used to make drive failure predictions. We’ll be doing a review of these publications in the next couple of months and hopefully shed some light on the ability to use AI to accurately make drive failure predictions in a timely manner.
The Hard Drive Stats data
It has now been over 11 years since we began recording, storing, and reporting the operational statistics of the hard drives and SSDs we use to store data in the Backblaze data storage cloud. We look at the telemetry data of the drives, including their SMART stats and other health related attributes. We do not read or otherwise examine the actual customer data stored.
Over the years, we have analyzed the data we have gathered and published our findings and insights from our analyses. For transparency, we also publish the data itself, known as the Drive Stats dataset. This dataset is open source and can be downloaded from our Drive Stats webpage.
Ah, the 1980s. It brought us such classics as Ghostbusters, The Princess Bride, Tina Turner’s triumphant comeback, Pac-Man, and the original Apple Macintosh. Also, it gave us the birth of the internet, in which we figured out how to make all our computers one giant, powerful network held together initially by internet protocols (IPs) and, eventually, by a mutual love of cat videos.
Now, each of our devices that connect to the internet require a way to find and send information back and forth, which means they need an IP address. Most folks don’t type IP addresses into their search bar though—we use domain names (for example, www.backblaze.com). Which IP addresses correspond to which domain names is stored in a hierarchical and distributed database system known as the domain name system (DNS), which is also an internet protocol.
Today, let’s talk about IP addresses: What are IPv4 and IPv6, why is IPv6 necessary, and what impact will it have on networking?
Let’s set the scene
Any time you’re sending and receiving data, be it a letter in the mail, dialing a phone number, or loading a website, you’ve got to have an identifiable address reach the proper person and/or device. What all of these types of addresses have in common is that as our population has exploded, we’ve had to re-work how addresses work in order to include more possible data locations. U.S. zip codes were established in 1963. Area codes were established in 1947, and a great expansion was necessary only three(ish) decades later, and that plan was implemented starting in the late 1980s and ending in the mid ’90s.
IP addresses, meanwhile, have been operating on the first and only protocol we introduced in the 1980s, called IPv4. Not only has the world population almost doubled since then, but there has also been a nonlinear explosion in internet-connected devices per person. When IP addresses were first invented, it was unfathomable that most folks would be walking around with a computer in their pocket, remotely checking who’s ringing their doorbells while adjusting their thermostat in anticipation of returning home. All of those internet-connected devices use an IP address, in one way or another.
So, it’s no surprise that we’re now seeing an adoption of a new IP address standard. In keeping with tradition, the versions aren’t sequential: Right now we’re jumping from IPv4 to IPv6. (What happened to IPv5? It was skipped, sort of.)
What is IPv4?
IPv4 is an internet protocol that assigns addresses to devices. It uses a 32-bit address, represented by four numbers (octets), each between 0 and 255, separated by dots (e.g., 192.168.1.100), and uses decimal notation.
Remember that each bit represents one of two possible values, a 0 or a 1. So, for a 32-bit value, there are 2^32 possible addresses, or 4,294,967,296 IP addresses total. Several IPv4 address blocks were also reserved for private networks and multicast addresses, about 286 million total. Between the two reserved blocks of addresses, that’s about 7% of the total addresses in existence.
What is IPv6?
IPv6 uses a 128-bit address, represented by a longer string of numbers and letters (e.g., 2001:0db8:85a3:0000:0000:8a2e:0370:7334) in hexadecimal code, aka hex code. If you’ve ever designed a MySpace page (hi, Tom!) or a webpage, you’re likely familiar with the hex codes used to identify precise colors.
Doing the math as we did above, there are 2^128 possible IPv6 addresses, which is 340 undecillion. (That’s the 11th order of magnitude if you’re going, million, billion, trillion, and so on.) And, just like IPv4, there are some reserved addresses, but they represent such a comparatively smaller number of total available addresses that it’s not even worth calculating a percentage.
Woah, how have we been surviving in the meantime?
We mentioned above that we’ve known we’re running out of IP addresses for a while. But, important detail: There was evidence of the problem as early as 1981, and mitigation efforts were enacted by 1992. Before we get into what mitigation strategies have been used over the years, a bit of a refinement of the above information—IP addresses consist of two main parts, one that identifies the network (or, sometimes, the subnet) and the host, or the destination on that network. (That’s true of both IPv4 and IPv6.)
Classful networking
In the original iteration of IPv4, the bits that identified the subnet were fixed, and that meant a lot of wasted space. In 1981, we implemented classful networking. Instead of keeping a fixed number of bits to identify a network, the three most significant bits identified the size of the network prefix, and that sent you to different classes. That meant that existing addresses didn’t have to change. Here’s a handy table:
Class
Most significant bits
Network prefix size (bits)
Host identifier size (bits)
Address range
Maximum number of networks
Maximum number of hosts per network
A
0
8
24
0.0.0.0–127.255.255.255
128 networks
16,777,216 hosts per network
B
10
16
16
128.0.0.0–191.255.255.255
16,384 networks
65,386 hosts per network
C
110
24
8
192.0.0.0–223.255.255.255
2,097,152 networks
256 hosts per network
D (multicast)
E (reserved)
1110
1111
—
—
224.0.0.0–255.255.255.255
—
—
All that sounds a bit like gobbley-gook. An analogy: You live in a city that wants to improve mail delivery, so it’s introduced the option to choose from a small, medium, or large mailbox. The sizes are actually pretty disproportionate—the small is about the size of a toaster, whereas the medium is the size of a kitchen trash can. (And large is the size of your car. Who gets that much mail?) No matter which size mailbox you (or your neighbor) chooses, your physical address didn’t change when this system was implemented. You usually get more mail than the toaster would accommodate, but never even come close to filling your trash can-sized mailbox. So, that extra space just sits empty and unused, never fulfilling its mail volume potential.
Note that classful networking is now largely defunct, replaced by…
Classless inter-domain routing (CIDR)
The biggest issue of the above system was its inflexibility. Adding classes gave us more flexibility than the original design, but you were still restricted to 8, 16, or 24 bits to identify the network. That means you can end up with a lot of unused IP addresses, as indicated by our above analogy. Here’s the math behind why:
The number of addresses available on a network is the inverse of how many bits you use to define it. So, in a 32-bit address, if you use 16 bits to define the network, you have 8 bits leftover to define the host. That’s our Class C network, which contained 2^8 (256) IP addresses—not enough for most use cases. And, the next smallest subset, Class B, represented 2^16 IP addresses (65,536 total), which most organizations could not use efficiently. After DNS became the norm, it became clear that classful networking wasn’t scalable, and thus CIDR rose to prominence.
CIDR is based on variable-length subnet masking (VLSM), which lets each network be divided into subnetworks of various power-of-two sizes. This method optimizes the allocation of IPv4 addresses by allowing for more flexible address blocks.
Using our analogy, instead of assigning mailbox size based on household size, you might just have a system in which folks walk up to the post office and find their name on a list associated with a mailbox. If someone has more or less mail that month, then they can be assigned the properly sized mailbox.
Network address translation (NAT)
NAT allows multiple devices to share a single public IPv4 address by modifying the IP header when it’s in transit. This is super useful when you’re talking about private networks—you can assign a single IP address to multiple devices. For example, if you have several internet of thing (IoT) devices in your home, they can all appear to the public network as one IP address, and your local network can figure out what traffic goes where. It also makes it so that if a network moves, the host doesn’t necessarily have to be assigned a new IP address, such as if an internet provider like Cox decides to stop doing business in your region, and Spectrum takes over their IP address allocation—though likely they’d just change your public IP address in that specific scenario.
In our mail analogy, NAT is like those group mailboxes you see in rural areas, apartment buildings, or in neighborhoods. Everyone in the same location gets their mail delivered to the same physical address, and your box number is used to further identify your house within the group mailbox.
The secondary market of IP addresses
If we can learn anything from the above workarounds, flexibility and possibility is key. So, it’s unsurprising to know that a secondary market has cropped up, introducing things like address recycling, address trading, and address leasing. IPv6 will solve the scarcity issue—but what else can it do?
What are the benefits of IPv6?
So far we’ve talked about the primary benefit of IPv6—more IP addresses that we clearly need. But, there are other benefits as well. Here’s a summary:
Improved Efficiency
Simpler header: The IPv6 header is simpler than IPv4’s, leading to faster packet processing and reduced overhead.
Efficient routing: IPv6’s design allows for more efficient routing, potentially reducing latency and improving network performance. Arguably, most folks won’t see a huge performance improvement unless they reconfigure their own network architecture, but the possibility is there.
Autoconfiguration: IPv6 supports automatic configuration of network interfaces, simplifying setup and reducing administrative overhead.
Enhanced Security
Built-in security features: IPv6 offers built-in security mechanisms like IPsec, potentially providing better protection against attacks. In practice, it’s not typically implemented as most encryption is typically handled at the transport layer security (TLS) IP layer.
Quality of Service (QoS)
Improved QoS: IPv6 provides better support for QoS, allowing for prioritization of different types of traffic, ensuring a better user experience for applications like video conferencing and online gaming.
Other Benefits
Reduced reliance on NAT: IPv6 reduces the need for NAT, simplifying network configurations and improving end-to-end connectivity.
Support for new services: IPv6 is better suited for emerging technologies and applications that require a large number of addresses and advanced features.
What’s next? Will we run out again?
Given the amount of addresses for IPv4 vs. IPv6 (4.2 billion vs. 340 undecillion, respectively), you can understand how we might have needed to shore up our IPv4 addresses. Honestly, if you assume one device per person, we already outnumber IPv4 addresses—in fact, we outnumbered IP addresses in the 1970s, before IPv4 was even invented! You shouldn’t assume one device per person, by the way. While many countries with widespread broadband access have several devices per person—in the U.S., Consumer Affairs was reporting 21 per U.S. household in 2023, and the average U.S. household for that same year was 2.51 people. Globally, that same source reports 3.6 internet-connected devices per person.
Changes like this can certainly be disruptive, but the good news on that front is that most devices will be dual-stacked for quite a while. That means that you’ll have both versions of an IP address, and this change can roll out organically (so to speak). In the end, we’ll have a better-performing internet, ready to grow with us for the foreseeable future.
The use of containers for software deployment has emerged as a powerful method for packaging applications and their dependencies into single, portable units. Containers enable developers to create, deploy, and run applications consistently across various environments. However, as containerized applications grow in scale and complexity, efficiently deploying, managing, and terminating containers can become a challenging task.
The growing need for streamlined container management has led to the rise of container orchestration—an automated approach to deploying, scaling, and managing containerized applications. Because it simplifies the management of large-scale, dynamic container environments, container orchestration has become a crucial component in modern application development and deployment.
In this blog post, we’ll explore what container orchestration is, how it works, its benefits, and the leading tools that make it possible. Whether you are new to using containers or looking to optimize your existing strategy, this guide will provide insights that you can leverage for more efficient and scalable application deployment.
What are containers?
Before containers, developers often faced the “it works on my machine” problem, where an application would run perfectly on a developer’s computer but fail in other environments due to differences in operating systems (OS), dependencies, or configuration.
Containers solve this problem by packaging applications with all their dependencies into single, portable units, improving consistency across different environments. This greatly reduces the compatibility issues and simplifies the deployment process.
As a lightweight software package, containers include everything needed to run an application such as code, runtime environment, system tools, libraries, binaries, settings, and so on. They run on top of the host OS, sharing the same OS kernel, and can run anywhere—on a laptop, server, in the cloud, etc. On top of that, containers remain isolated from each other, making them more lightweight and efficient than virtual machines (VMs), which require a full OS for each instance. Check out our article to learn more about the difference between containers and VMs here.
Containers provide consistent environments, higher resource efficiency, faster startup times, and portability. They differ from VMs in that they share the host OS kernel. While VMs virtualize hardware for strong isolation, containers isolate at the process level. By solving the longstanding issues of environment consistency and resource efficiency, containers have become an essential tool in modern application development.
What is container orchestration?
As container adoption has grown, developers have encountered new challenges that highlight the need for container orchestration. While containers simplify application deployment by ensuring consistency across environments, managing containers at scale introduces complexities that manual processes can’t handle efficiently, such as:
Scalability: In a production environment, applications often require hundreds or thousands of containers running simultaneously. Manually managing such a large number of containers becomes impractical and error-prone.
Resource management: Efficiently utilizing resources across multiple containers is critical. Manual resource allocation leads to underutilization or overloading of hardware, negatively impacting performance and cost-effectiveness.
Container failure management: In dynamic environments, containers can fail or become unresponsive. Developers need a way to create a self-healing environment, in which failed containers are automatically detected, then recover without manual intervention to ensure high availability and reliability.
Rolling updates: Deploying updates to applications without downtime and the ability to quickly roll back in case of issues are crucial for maintaining service continuity. Manual updates can be risky and cumbersome.
Container orchestration automates the deployment, scaling, and management of containers, addressing the complexities that arise in large-scale, dynamic application environments. It ensures that applications run smoothly and efficiently, enabling developers to focus on building features rather than managing infrastructure. Container orchestration tools provide various features such as automated scheduling, self-healing, load balancing, and resource optimization to deploy and manage applications more effectively to ensure reliability, performance, and scalability.
What are the benefits of container orchestration?
Container orchestration offers many different advantages that streamline the deployment and management of containerized applications. We’ve touched on a few of them, but here’s a concise list:
Enhanced scalability: Easily scale applications up or down to meet changing demands.
Increased reliability: Automatic health checks and container replacement ensure high availability.
Simplified management: Centralized control and automation reduce the complexity of managing large-scale containerized applications.
Faster deployments: Orchestrators enable rapid and consistent deployments across different environments.
Cost efficiency: Better resource utilization and automation, leading to cost savings.
How does container orchestration work?
Now that we understand what container orchestration is, let’s take a look at how container orchestration works using the example of Kubernetes, one of the most popular container orchestration platforms.
In the above diagram, we see an example of container orchestration in action. The system is divided into two main sections: the control plane and the worker nodes.
Control plane
The control plane is the brain of the container orchestration system. It manages the entire system, ensuring that the desired state of the applications is maintained. Key components of the control plane include:
Configuration store (etcd): A distributed key-value store that holds all the cluster data, such as the configuration and state information. Think of it as a central database for the cluster.
API server: The front-end of the control plane, exposing the orchestration API. It handles all the communication within the cluster and with external clients.
Scheduler: Assigns workloads to nodes based on resource availability and scheduling policies, ensuring efficient resource utilization.
Controller manager: Runs various controllers that handle routine tasks to maintain the cluster’s desired state.
Cloud control manager: Interacts with cloud provider APIs to manage cloud specific resources, integrating the cluster with cloud infrastructure.
Worker nodes
Worker nodes, virtual machines, and bare metal servers are all common options for where to run application workloads. Each worker node has the following components:
Node agent (kubelet): An agent that ensures the containers are running as expected. It communicates with the control plane to receive instructions and report back on the status of the nodes.
Network proxy (kube-proxy): Maintains network rules on each node, facilitating communication between containers and services within the cluster.
Within the worker nodes, pods are the smallest deployable units. Each pod can contain one or more containers that run the application and its dependencies. The diagram shows multiple pods within the worker nodes, indicating how applications are deployed and managed.
The cloud provider API directs how the orchestration system dynamically interacts with cloud infrastructure to provision resources as needed, making it a flexible and powerful tool for managing containerized applications across various environments.
Popular container orchestration tools
Several container orchestration tools have emerged as the leaders in the industry, each offering unique features and capabilities. Here are some of the most popular tools:
Kubernetes
Kubernetes, often referred to as K8s, is an open-source container orchestration platform initially developed by Google. It has become the industry standard for managing containerized applications at scale. K8s is ideal for handling complex, multi-container applications, making it suitable for large-scale microservices architectures and multi-cloud deployments. Its strong community support and flexibility with various container runtimes contribute to its widespread adoption.
Docker Swarm
Docker Swarm is Docker’s native container orchestration tool, providing a simpler alternative to Kubernetes. It integrates seamlessly with Docker containers, making it a natural choice for teams already using Docker. Known for its ease of setup and use, Docker Swarm allows quick scaling of services with straightforward commands, making it ideal for small to medium-sized applications and rapid development cycles.
Amazon Elastic Container Service (ECS)
Amazon ECS (Elastic Container Service) is a fully managed container orchestration service provided by AWS, designed to simplify running containerized applications. ECS integrates deeply with AWS services for networking, security, and monitoring. ECS leverages the extensive range of AWS services, making it a straightforward orchestration solution for enterprises using AWS infrastructure.
Red Hat OpenShift
Red Hat OpenShift is an enterprise-grade Kubernetes container orchestration platform that extends Kubernetes with additional tools for developers and operations, integrated security, and lifecycle management. OpenShift supports multiple cloud and on-premise environments, providing a consistent foundation for building and scaling containerized applications.
Google Kubernetes Engine (GKE)
Google Kubernetes Engine (GKE) is a managed Kubernetes service offered by Google Cloud Platform (GCP). It provides a scalable environment for deploying, managing, and scaling containerized applications using Kubernetes. GKE simplifies cluster management with automated upgrades, monitoring, and scalability features. Its deep integration with GCP services and Google’s expertise in running Kubernetes at scale make GKE an attractive option for complex application architectures.
Embracing the future of application deployment
Container orchestration has undoubtedly revolutionized the way we deploy, manage, and scale applications in today’s complex and dynamic software environments. By automating critical tasks such as scheduling, scaling, load balancing, and health monitoring, container orchestration enables organizations to achieve greater efficiency, reliability, and scalability in their application deployments.
The choice of orchestration platform should be carefully considered based on your specific needs, team expertise and long term goals. It is not just a technical solution but a strategic enabler, providing you with significant advantages in your development and operational workflows.
Your QNAP network attached storage (NAS) device helps your business centralize storage capacity, support collaboration, and access files 24/7 from anywhere. If you were relying on individual hard drives or another ad hoc storage solution before, it definitely helps you uplevel your data management practices.
One of the great features of a QNAP NAS device is Hybrid Backup Sync (HBS), its onboard backup utility that allows you to easily store a copy of your data to your NAS and other destinations. You can set regular, automated backups to protect against data loss due to hardware failures or accidental deletion. But, keeping a copy of your data on your NAS alone doesn’t constitute a true backup strategy. For that, you need to follow the 3-2-1 backup rule with at least one copy stored off-site.
This post explains how to set up a 3-2-1 backup strategy with your QNAP NAS. We’ll share the benefits of storing your backups in the cloud, discuss different options for backing up your QNAP NAS, and provide some practical examples of what you can do by combining cloud storage and your NAS.
QNAP NAS and a 3-2-1 backup strategy
Following the 3-2-1 strategy means having three copies of your data, two of which are stored locally but on different media (aka devices), and one stored off-site.
Your QNAP NAS is your first step towards completing the 3-2-1 strategy. By using it to store data locally, you have two copies on-site. Backing up your QNAP NAS to the cloud completes the 3-2-1 strategy by serving as your off-site storage.
You could maintain an off-site copy on another physical device like another NAS, an external drive, or a file server, but keep in mind, backing up to an external destination other than the cloud will require you to physically separate the backup copy—that is, send your drive via mail or drive it elsewhere in order to ensure geographic separation. Backing up your QNAP NAS to the cloud means you achieve a 3-2-1 strategy without going out of your way to physically separate the copies, and it allows you to easily store data in different regions for greater data resilience and disaster recovery.
The additional benefits of backing your QNAP NAS to the cloud
Backing up your QNAP NAS to the cloud gives you a number of additional benefits, including:
Disaster recovery: Without an off-site backup, your on-site data, including data on your individual workstations and your NAS, is susceptible to data loss. Natural disasters could wipe out your machines, your NAS, and any other backups you might store locally. Cloud backups safeguard your data from physical disasters that could destroy both your NAS and local copies.
Ransomware protection: While QNAP has on-board utilities that allow you to revert to a previous backup, your NAS is still connected to your network and susceptible to ransomware. Cloud backups, especially those configured with Object Lock, provide a layer of security against ransomware attacks that can encrypt or delete data stored on your network-connected NAS.
Protection against hardware failure: Because your NAS is likely set up in a RAID configuration, one drive failure might not affect your data. But, while one drive is down, your data is at a higher risk. If another drive were to fail, you could lose data. Keeping an off-site backup in cloud storage helps you avoid this fate.
Accessibility: With your data in the cloud, your backups are accessible from anywhere. If you’re away from your desk or office and you need to retrieve a file, you can simply log in to your cloud account and copy that file down.
Security: Cloud vendors typically protect customer data by encrypting it as it travels to its final destination and/or when it is at rest on the vendors’ storage servers. Encryption protocols differ between cloud vendors, so make sure to understand them as you’re evaluating cloud providers, especially if you have specific security requirements.
Automation: Your QNAP NAS comes with a built-in backup utility so you can set your cloud backup schedule in advance and avoid human error (like forgetting to back up) in the future.
Scalability: As your data grows, your cloud backups grow with it. With cloud storage, there’s no need to invest in or maintain additional hardware to ensure your data is properly backed up.
How to protect your business data with QNAP
QNAP offers a number of different tools and functionality to help you back up business devices and systems to your NAS, including:
Qsync: Qsync is an on-board backup utility on QNAP devices that allows you to sync computer files to your QNAP NAS. This allows you to back up workstations to your NAS, creating a second, local copy of that data. QNAP NAS also supports Time Machine for Macs.
NetBack PC Agent: A utility specifically for backing up Windows PCs and servers.
Hyper Data Protector: Use Hyper Data Protector to back up multiple VMware and Hyper-V virtual machines (VMs).
File server backup: QNAP devices support multiple protocols, including rsync, FTP, and CIFS for backing up different file servers.
Boxafe: Use Boxafe to back up Google workspace and Microsoft 365 business account data to your NAS.
Snapshot feature: Takes point-in-time copies of data for protection and recovery.
MARS: Use QNAP’s MARS service to back up Google Photos and WordPress databases and files to your NAS.
How to back up your QNAP to the cloud
Once you’ve created a copy of your business data to your QNAP NAS, you can then use QNAP Hybrid Backup Sync to back it up to the cloud. Hybrid Backup Sync supports multi-version backups and allows you to customize retention settings for version management. QNAP’s QuDedup feature deduplicates data, helping you manage your storage footprint. The utility also allows you to manage Time Machine backups for Mac devices.
What can you do with cloud storage and QNAP Hybrid Backup Sync?
The QNAP Hybrid Backup Sync app provides you with a lot of options. You can synchronize in the cloud as little or as much as you want. Here are some practical examples of what you can do with Hybrid Backup Sync and cloud storage working together.
1. Sync the entire contents of your QNAP to the cloud
The QNAP NAS has excellent fault tolerance—it can continue operating even when individual drive units fail—but nothing in life is foolproof. It pays to be prepared in the event of a catastrophe. Now that you know about the 3-2-1 backup strategy, you know how important it is to make sure that you have a copy of your files in the cloud.
2. Sync your most important media files
Using your QNAP to store marketing assets like video and photos? You’ve invested untold amounts of time, money, and effort into producing those media files, so make sure they’re safely and securely synced to the cloud with Hybrid Backup Sync.
3. Back up Time Machine and other local backups
Apple’s Time Machine software provides Mac users with reliable local backup, and many Backblaze customers rely on it to provide that crucial first step in making sure their data is secure. QNAP enables the NAS to act as a network-based Time Machine backup. Those Time Machine files can be synced to the cloud, so you can make sure to have Time Machine files to restore from in the event of a critical failure.
If you use Windows or Linux, you can configure the QNAP NAS as the destination for your Windows or Linux local data backup. That, in turn, can be synced to the cloud from the NAS.
Ready to give it a try?
Hybrid Backup Sync allows you to choose from any number of cloud storage providers as a backup destination, and Backblaze B2 Cloud Storage is one of them. Check out our videos on how to use Hybrid Backup Sync to back up or sync your data to B2 in under 15 minutes.
If you haven’t given cloud storage a try yet, you can get started now and make sure your NAS is synced or backed up securely to the cloud.
At the risk of being called the stick in the mud of the tech world, we here at Backblaze have often bemoaned our industry’s love of making up new acronyms. The most recent culprit, hailing from the fast-moving artificial intelligence/machine learning (AI/ML) space, is truly memorable: RAG, aka retrieval-augmented generation. For the record, its creator has apologized for inflicting it upon the world.
Given how useful it is, we’re willing to forgive. (I’m sure he was holding his breath for that news.) Today, our AI 101 series is back to talk about what RAG is—and the big problem it solves.
Read more AI 101
This article is part of a series that attempts to understand the evolving world of AI/ML. Check out our previous articles for more context:
LLMs are the most recognizable expression of AI in our current zeitgeist. (Arguably, you could append that with “that we’re all paying attention to,” given that ML algorithms have been behind many tools for decades now.) LLMs underpin tools like ChatGPT, Google Gemini, and Claude, as well as things like service-oriented chatbots, natural language processing tasks, and so on. They’re trained on vast amounts of data with algorithmic guardrails known as parameters and hyperparameters guiding their training. Once trained, we query them through a process known as inference.
Fabulous! The possibilities are endless. However, one of the biggest challenges we’ve experienced (and laughed about on the internet) is that LLMs can return inaccurate results, while sounding very, very reasonable. Additionally, LLMs don’t know what they don’t know. Their answers can only be as good as the data they draw from—so, if their training dataset is outdated or contains a systematic bias, it will impact your results. As AI tools have become more widely adopted, we’ve seen LLM inaccuracies range from “funny and widely mocked” to “oh, that’s actually serious.”
Shoutout to Reddit users for finally getting this one into trusted sources.
Shoutout to Reddit users for finally getting this one into trusted sources.
Shoutout to Reddit users for finally getting this one into trusted sources.
Enter retrieval-augmented generation (Fine! RAG)
RAG is a solution to these problems. Instead of relying on only an LLM’s dataset, RAG queries external sources before returning a response. It’s more complicated than “let me google that for you,” as the process takes that external data, turns it into a vectored database, and then balances external data with an LLM’s “general knowledge” generated response and skill at responding to conversational queries.
This has several advantages. Users now have sources they can cite, and recent information is taken into account. From a development perspective, it means that you don’t have to re-train a model as frequently. And, it can be implemented in as few as five lines of code.
One important nuance is that when you’re building RAG into your product, you can set its sources. For industries like medicine and law, that means you can point them towards industry journals and trusted sources, outweighing the often misquoted or mis-cited examples you might see in a general database.
Another example: For a technical documentation portal, you can take an LLM, trained on general information and the nuts and bolts of conversational querying, and direct it to rely on your organization’s help articles as its most important sources. Your organization controls the authoritative data, and how often/when changes are made. Users can trust that they’re getting the most recent security patches and correct code. And, you can do so quickly, easily, and—most importantly—cost-effectively.
RAG is a great, straightforward method for keeping LLM tools updated with current, high-quality information and giving users more transparency around where their answers are coming from. However, as we mentioned above, AI is only ever as good as the data it uses. Keep in mind, that’s a deceptively simple thing to say. It’s an entire, specialized job to validate datasets, and that expertise is built into the research and monitoring that happens while training an LLM.
RAG gives a new source of data a privileged position—you’re saying “this data is more authoritative than that data” and, since the LLM doesn’t have anything in its general database, it may not have a counter argument. If you’re not paying attention to your RAG data source standards, and doing so on an ongoing basis, it’s possible, and even likely, that data bias, low quality data, etc. could creep into your model.
Think of it this way: If you’re pointing to a new feature in your tech docs and there’s an error, that impact is magnified because an LLM will give more weight to the RAG data. At least in that case, you’re the one who controls the source data. In our other examples of legal or medical AI tools pointing to journal updates, things can get, well, more complicated. If (when) you’re setting up an AI that uses RAG, it’s imperative to make sure you’re also setting yourself up with reliable sources that are regularly updated.
But, given its impact, and how low of a lift it is to integrate into existing products, we can see why RAG is all the RAGe—and, as always, we look forward to more to come in the AI landscape. For now, we can already see the impact it’s having on the market, with SaaS companies and startups alike exploring the possibilities.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.