Tag Archives: games

Accelerate multiplayer game hosting with AWS m8azn instances

Post Syndicated from Spencer Myers original https://aws.amazon.com/blogs/compute/accelerate-multiplayer-game-hosting-with-aws-m8azn-instances/

Online multiplayer gaming continues to grow, with players demanding lower latency, higher concurrency, and more immersive experiences than ever before. For game studios hosting dedicated multiplayer servers on AWS, infrastructure decisions directly impact player experience and retention, server tick rates, and ultimately, revenue.

Games are becoming more computationally demanding while offering richer gameplay experiences. Studios need instances that maintain consistent player experiences in increasingly complex and dense computational game experiences.

In this post, we explore how AWS m8azn instances powered by AMD’s 5th gen EPYC processors perform with a real game: Mob Rush. M8azn instances offer up to 2x compute performance and 5 GHz CPU frequency compared to previous generation M5zn instances, and up to 24% higher performance than M8a instances. M8azn instances deliver up to 4.3x higher memory bandwidth and 10x larger L3 cache compared to M5zn instances allowing latency-sensitive and compute-intensive workloads to achieve results faster. These instances also offer up to 2x networking throughput and up to 3x EBS throughput versus M5zn instances. This post walks through the deployment of the game and reviews the performance metrics across varying player counts.

When to choose m8azn for multiplayer hosting

Not every workload requires m8azn. Game modes that require high performance and low latency computation are ideal matches for m8azn instances. M8azn instances are ideal for games that benefit from higher compute performance, larger L3 cache, and higher memory bandwidth.

Ideal use cases

  • Session-based high density multiplayer games: Games with discrete match sessions that spin up and tear down servers dynamically benefit from the fast startup performance of m8azn and high player density per instance.
  • Physics-intensive game servers: Titles relying heavily on PhysX collision detection, rigid-body simulation, and real-time raycast operations see significant gains from improved FPU throughput.
  • Variable player load scenarios: Live service games with daily peak hours or seasonal events benefit from the cost efficiency at both low and high utilization levels.
  • High-density hosting: Studios seeking to maximize concurrent game sessions per instance to reduce per-player infrastructure cost.

Mob Rush

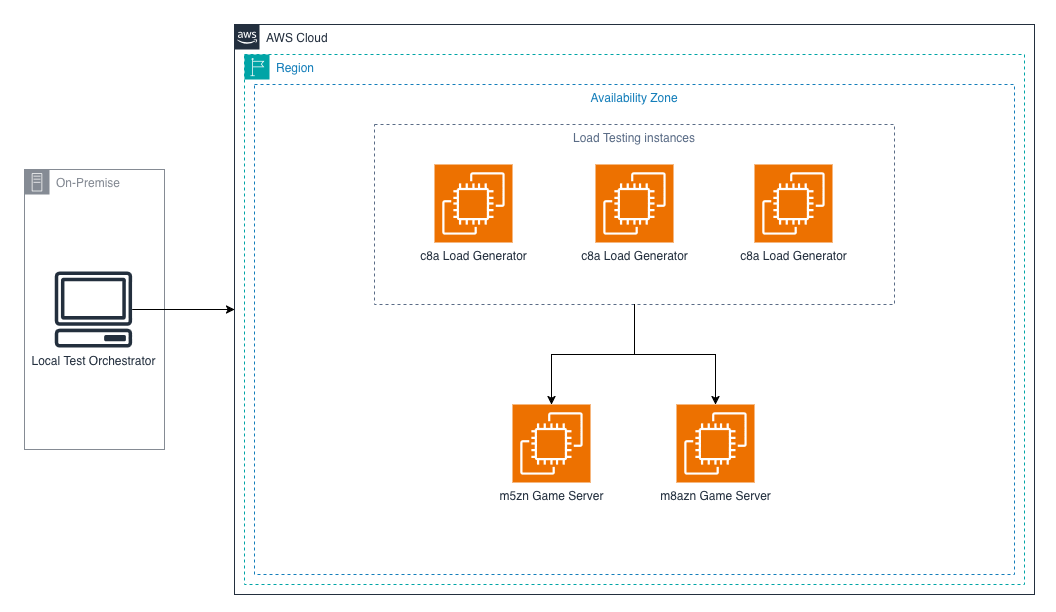
In this post, we run the game Mob Rush. Mob Rush is a multiplayer game where players collect and grow a crowd in a war of numbers style competition. Mob Rush is built with the Unity game engine. Our test infrastructure includes a local test orchestrator, two game servers, and a series of load generation servers. The following diagram shows our testing setup:

Figure 1: Mob Rush Load Testing Diagram

Load testing configuration

Our load testing scenario compares the m5zn instance that our game currently runs on with the new m8azn to decide if the new instance is a migration candidate. We compare player experience metrics (FPS, tick-rate, and others) and instance performance metrics (CPU utilization, tick-rate, players per server, and others) to see how well Mob Rush runs on newer hardware.

Methodology

Benchmarks were conducted using a Unity multiplayer game server build, simulating concurrent player connections with synthetic load generation. Our current game servers perform well to around 4,000 simultaneous player connections before the player experience started to degrade as the server was overloaded. For our benchmarks we have tested each instance type at the 3,000 player threshold, and then increased to 4,000 players, 6,000 players and 8,000 players and recorded how each instance performed.

Parameter Configuration
Instance Types m8azn.xlarge (4 vCPU, 16 GB) vs. m5zn.xlarge (4 vCPU, 16GB)
OS / AMI Ubuntu 22.04 LTS
Unity Version Unity 2020.3.12f1, headless Linux build
Concurrency Scenarios Gradual ramp from zero players to number of players that overload the instance causing player experience impact
Metrics Collected Connection success rate, connection latency (avg/P50/P95/P99/max), batch processing time, run queue depth, context switches/second, softirq/second, TCP retransmits, listen overflows
Test Duration 562 seconds total (202 s ramp at 100 connections/sec + 360 s sustained hold)

Results

Our testing results are displayed in the following charts. The new m8azn instances start to shine as load increases. M5zn instances start to have significant latency spikes and max latency numbers once we get to around 6,000 CCU, which severely impacts the player experience. We can push the m8azn instances to 8,000 CCU before experiencing player impact or introducing any latency spikes >500ms.

Metric m5zn.2xlarge m8azn.2xlarge
Player Count 3,000
Average Latency 9.7ms 8ms
P99 Latency 22ms 28ms
Max Latency 43ms 23ms
Peak Run Queue 575 14
TCP Re-transmits 0 0
Latency Spikes > 500ms 0 0
Errors 0 0
Metric m5zn.2xlarge m8azn.2xlarge
Player Count 4,000
Average Latency 8.6ms 7.2ms
P99 Latency 29ms 24ms
Max Latency 76ms 29ms
Peak Run Queue 451 24
TCP Re-transmits 0 0
Latency Spikes > 500ms 0 0
Errors 0 0
Metric m5zn.2xlarge m8azn.2xlarge
Player Count 6,000
Average Latency 6.8ms 6.5ms
P99 Latency 22ms 22ms
Max Latency 29ms 27ms
Peak Run Queue 318 27
TCP Re-transmits 0 0
Latency Spikes > 500ms 0 0
Errors 0 0
Metric m5zn.2xlarge m8azn.2xlarge
Player Count 8,000
Average Latency 25ms 9.7ms
P99 Latency 542ms 27ms
Max Latency 2386ms 238ms
Peak Run Queue 651 87
TCP Re-transmits 0 0
Latency Spikes > 500ms 97 0
Errors 0 0

Price-performance comparison for 100k CCU

One methodology to calculating price/performance of these instances is to compare the cost of running enough instances to serve 100,000 players while maintaining an optimal and minimal latency player experience. All prices discussed in this section are based on us-east-1 OnDemand Linux pricing at the time of writing.

To serve 100k CCU with m5zn.xlarge instances, we would need to provision approximately 20 m5zn.xlarge instances (each instance can support 5,000 CCU before player experience degrades). Each m5zn.xlarge costs $0.3303/hr. That brings our hourly cost to $6.606/hr per 100k CCU.

In comparison, we only need 13 m8azn.xlarge instances to serve 100k CCU, thanks to the ~61% performance improvement of average latency of m8azn at 8,000 CCU per instance. Each m8azn.xlarge costs $0.4129/hr. Our hourly cost for 100k CCU in this scenario is $5.3677/hr. M8azn instances clearly demonstrate better price performance when compared to m5zn instances.

Conclusion

M8azn instances represent a compelling upgrade path for multiplayer game studios currently running on older generation instances. The combination of AMD EPYC processor improvements, enhanced memory bandwidth, and superior network performance delivers measurable benefits across the workloads that matter most for game hosting.

Try out m8azn in your development environment and calculate price/performance gains to see if m8azn is right for your workload. The Optimizing EC2: Hands-on Strategies for Cost-effective Performance workshop can guide you in comparing performance and calculating your overall price/performance savings across different instances.

Additional Resources

How Zynga scaled multi-warehouse data governance with Amazon Redshift federated permissions

Post Syndicated from Johan Eklund, Matthew Wongkee, Noelia Tardón original https://aws.amazon.com/blogs/big-data/how-zynga-scaled-multi-warehouse-data-governance-with-amazon-redshift-federated-permissions/

Zynga, a global leader in interactive entertainment operates a portfolio of mobile game studios including Socialpoint, the creators of Dragon City and Monster Legends. Zynga’s analytics platform processes telemetry and revenue data across studios using Amazon Redshift as its central data warehouse.

As Zynga expanded its analytics architecture to include individual studios with their own compute environments, the team faced a challenge: how to maintain centralized data governance while granting studios independent query capacity. Their existing approach to permission management introduced lag and required custom infrastructure if scaled to multiple warehouses.

In this post, we walk through how Zynga adopted Amazon Redshift federated permissions and AWS IAM Identity Center to enforce consistent, tiered data access across provisioned and serverless Amazon Redshift environments without building custom synchronization pipelines.

The challenge

Zynga needed to onboard Socialpoint’s current Amazon Redshift workloads and make Zynga’s central data available to them. Zynga’s existing production cluster would house the Socialpoint raw data, but the compute would come from another warehouse set up as a consumer. At the same time, Zynga’s data access control policies would need to be enforced across all warehouses. Zynga uses a tiered access control policy which would need to be synced across all consumers with no permission lag or manual grant synchronization.

During the migration, Socialpoint’s specific extract, transform, and load (ETL) processes would be included in Zynga’s central ETLs and their data ingestion pipeline would be replaced by Zynga’s latest generation of data ingestion infrastructure. Because the migration process happens in stages, Amazon Redshift sizing would also gradually need to increase.

The team evaluated two alternatives before arriving at a solution:

  • AWS Lake Formation couldn’t manage local and cross-cluster permissions using the same interface, and required AWS Access and Identity Management (IAM) or IAM Identity Center authentication for all users including service accounts.
  • Manual grants on consumer clusters introduced a delay between when permissions were updated on the producer and when they took effect on the consumer. This approach would also require an external job that synced permissions and would be unlikely to scale well beyond 2–3 consumers.

Solution overview

Zynga implemented a solution using three AWS services working together:

  1. Amazon Redshift federated permissions enabled cross-cluster queries without explicit data shares. Permissions granted on the producer cluster propagate immediately to consumer workgroups through AWS Glue Data Catalog registration.
  2. AWS IAM Identity Center provides unified authentication through federation with Okta. When users sign in, their Okta group memberships are provisioned through a System for Cross-domain Identity Management (SCIM) and automatically map to Amazon Redshift roles, removing the need for external synchronization jobs.
  3. Amazon Redshift Serverless provides the compute layer for Socialpoint, scaling to zero when idle and avoiding the need to pre-size a provisioned cluster during the migration period.

The architecture uses a dual-grant approach where every permission is granted to both an IAM Identity Center group (for users) and a federated IAM role (for service accounts). This gives both authentication paths the same access.

How it works

Authentication with IAM Identity Center

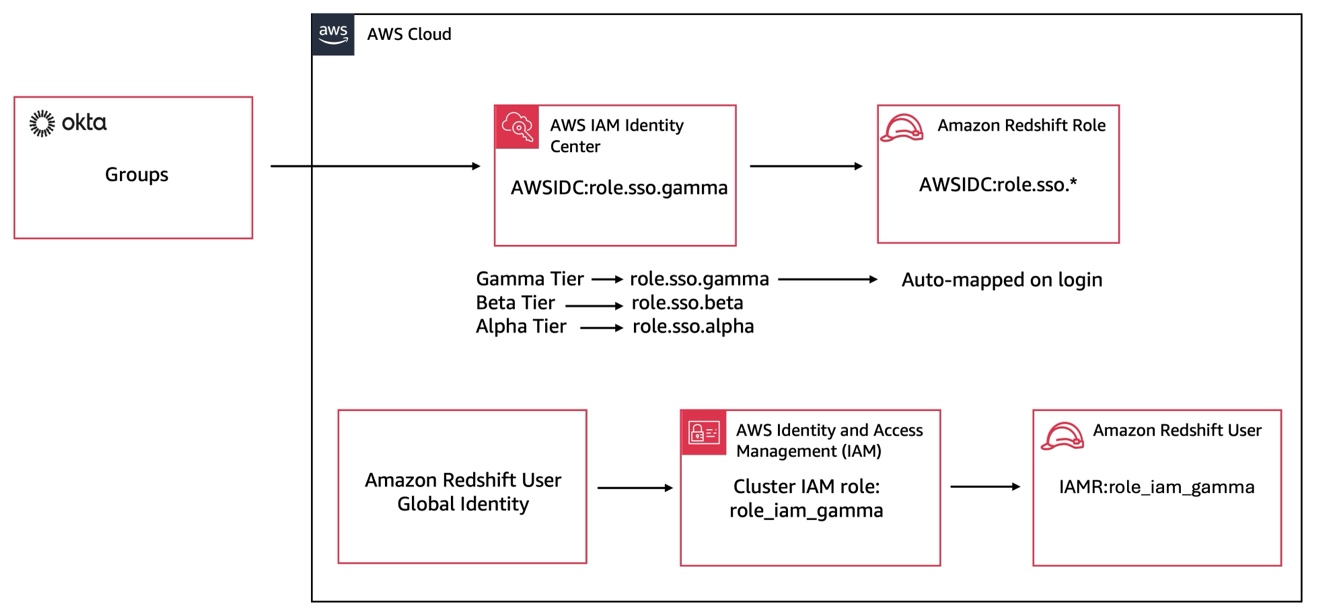
Zynga’s existing Okta directory syncs to IAM Identity Center, which is connected to the Amazon Redshift Serverless workgroup. When a user authenticates, Amazon Redshift automatically creates a user mapped to their email address and assigns them to roles based on their Okta group membership.

For example, an analyst in the Gamma Tier group signs in and is automatically assigned the AWSIDC:role.sso.gamma role in Amazon Redshift. No manual role assignment or synchronization job is required.

Service accounts, used for programmatic access, authenticate differently. Either using their IAM role and calling the get-credentials API, or by using the new federated permissions feature. Each service account assumes a federated IAM role, which creates a corresponding federated user in Amazon Redshift (for example, IAMR:role_iam_gamma).

The identity layer shows two authentication paths. Interactive users authenticate through Okta, which syncs group memberships to AWS IAM Identity Center. On login, IAM Identity Center automatically maps users to tiered Amazon Redshift roles (AWSIDC:role.sso.gamma, beta, alpha). Service accounts take a separate path, assuming a cluster IAM role that creates a corresponding federated user (IAMR:role_iam_gamma) in Amazon Redshift.

Figure 1 – Identity layer

The dual-grant approach

To ensure that both users and service accounts can access the same data, every read permission is granted to both the IAM Identity Center group and the federated IAM role in a single statement:

GRANT SELECT ON schema.table TO
	'IAMR:role_iam_gamma',
	ROLE 'AWSIDC:role.sso.gamma';

Transitioning the producer cluster

The shared provisioned cluster already had active users with local grants. To avoid disruption, Zynga implemented a tri-grant approach on the producer during the transition period. Existing stored procedures were modified to grant permissions to three targets: the legacy local role, the IAM Identity Center group, and the federated IAM role.

GRANT SELECT ON schema.table TO
	ROLE role_rs_gamma,
	ROLE 'AWSIDC:role.sso.gamma','IAMR:role_iam_gamma';

This approach maintains backward compatibility for existing users on the producer while enabling immediate access from the new serverless workgroup. The long-term plan includes migration of all producer users to IAM Identity Center and retire the legacy local grants.

Stored procedures for consistent governance

Rather than requiring users to construct dual-grant statements manually, Zynga created stored procedures that encapsulate the grant logic:

  • grant_read accepts a table name and access tier, then issues the appropriate dual-grant for both the IAM Identity Center group and the federated IAM role.
  • grant_write grants data definition language (DDL) and data manipulation language (DML) permissions to the appropriate team-based role.

This provides a consistent interface for permission management regardless of which cluster or workgroup that the user is on.

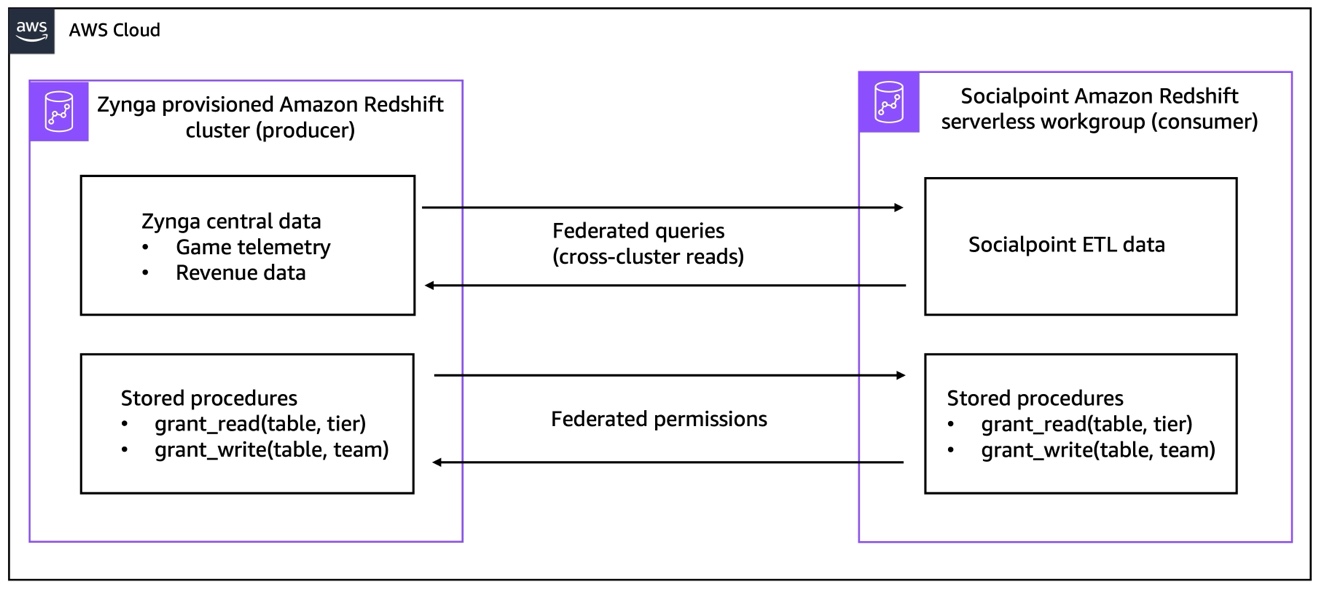
Architecture diagram in the AWS Cloud showing a federated Amazon Redshift setup. On the left, a Zynga provisioned Amazon Redshift cluster (producer) holds Zynga central data — game telemetry and revenue data — and stored procedures grant_read(table, tier) and grant_write(table, team). On the right, a Socialpoint Amazon Redshift Serverless workgroup (consumer) holds Socialpoint ETL data and the same two stored procedures. Bidirectional arrows between the two environments label the top connection as "Federated queries (cross-cluster reads)" between the data stores, and the bottom connection as "Federated permissions" between the stored procedures.

Figure 2 – Data and compute layer

Results

The migration delivered measurable improvements:

  • Immediate permission propagation – Grants on the producer cluster took effect on the consumer workgroup instantly, replacing a process that previously required manual intervention and introduced lag.
  • Zero additional infrastructure cost – Federated permissions, federated queries, and IAM Identity Center added no incremental costs to the architecture.
  • Removed custom synchronization – The team removed the need for Lake Formation configurations, external AWS Lambda functions, and Airflow workflows for permission management.
  • Scalable pattern – The same architecture can be extended to additional studio workgroups without duplicating permission management logic.

Lessons learned

Zynga adopted federated permissions shortly after the feature launched in US West Oregon (us-west-2) in January 2026. The team shared several observations from their early adoption:

  • Run a proof of concept first. The team validated the full permission model in a test environment before deploying to production, including testing that existing data shares to other clusters were not disrupted.
  • Plan for the dual-grant requirement. Because IAM Identity Center users and federated IAM roles are distinct identity types, every read permission requires two grants. Encapsulating this in stored procedures prevents errors and reduces cognitive overhead.
  • Start with serverless for new workloads. With Amazon Redshift Serverless, the team can avoid sizing decisions during the migration period. If usage patterns later justify it, they can migrate to a provisioned cluster from a serverless snapshot with minimal downtime.
  • Engage with AWS. As an early adopter of a new feature, Zynga maintained regular contact with the Amazon Redshift team through their AWS Technical Account Manager to report issues and request enhancements.

Conclusion

Zynga’s adoption of Amazon Redshift federated permissions demonstrates how organizations with multi-cluster Amazon Redshift architectures can enforce centralized data governance without building custom synchronization infrastructure. By combining federated permissions with IAM Identity Center and Amazon Redshift Serverless, the team established a pattern that scales to additional studios while maintaining consistent access controls and reducing operational overhead.

To learn more about the services used in this post, see the following resources:


About the authors

Johan Eklund

Johan Eklund is a Principal Software Engineer on the Data Engineering team at Zynga, focused on building and operating large-scale data platforms on AWS. Day-to-day, his work spans Redshift architecture, ETL orchestration, platform operations, and security and access control. Outside of work, Johan enjoys exploring art and music through creative coding and DIY hardware synthesizers.

Matthew Wongkee

Matthew Wongkee is a Principal Software Engineer at Zynga, where he builds scalable and high-performance data platforms and infrastructure, including Amazon Redshift. He focuses on enabling teams to leverage their data through self-service capabilities, including data discovery, query optimization, curated datasets, and data quality. In his spare time, he practices short track speed skating.

Noelia Tardón

Noelia Tardón is a Principal Software Engineer at Zynga. Based in Barcelona, she works on large-scale cloud data platforms with a focus on performance optimization and cost efficiency. She designs and builds data lake and data warehouse solutions while ensuring compliance with data protection regulations. Outside of work, she enjoys spending time with her family and running.

Sandeep Adwankar

Sandeep is a Senior Technical Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.

Satesh Sonti

Satesh is a Principal Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Photo of AUthor - Steve Phillips

Steve Phillips

Steve is a Principal Technical Account Manager and Analytics specialist at AWS in the North America region. Steve currently focuses on data warehouse architectural design, data lakes, data ingestion pipelines, and cloud distributed architectures.

Human Trust of AI Agents

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/04/human-trust-of-ai-agents.html

Interesting research: “Humans expect rationality and cooperation from LLM opponents in strategic games.”

Abstract: As Large Language Models (LLMs) integrate into our social and economic interactions, we need to deepen our understanding of how humans respond to LLMs opponents in strategic settings. We present the results of the first controlled monetarily-incentivised laboratory experiment looking at differences in human behaviour in a multi-player p-beauty contest against other humans and LLMs. We use a within-subject design in order to compare behaviour at the individual level. We show that, in this environment, human subjects choose significantly lower numbers when playing against LLMs than humans, which is mainly driven by the increased prevalence of ‘zero’ Nash-equilibrium choices. This shift is mainly driven by subjects with high strategic reasoning ability. Subjects who play the zero Nash-equilibrium choice motivate their strategy by appealing to perceived LLM’s reasoning ability and, unexpectedly, propensity towards cooperation. Our findings provide foundational insights into the multi-player human-LLM interaction in simultaneous choice games, uncover heterogeneities in both subjects’ behaviour and beliefs about LLM’s play when playing against them, and suggest important implications for mechanism design in mixed human-LLM systems.

Modernize game intelligence with generative AI on Amazon Redshift

Post Syndicated from Narendra Gupta original https://aws.amazon.com/blogs/big-data/modernize-game-intelligence-with-generative-ai-on-amazon-redshift/

Game studios generate massive amounts of player and gameplay telemetry, but transforming that data into meaningful insights is often slow, technical, and dependent on SQL expertise. With the new Amazon Redshift integration for Amazon Bedrock Knowledge Bases, teams can unlock instant, AI-powered analytics by asking questions in natural language. Analysts, product managers, and designers can now explore Amazon Redshift data conversationally—no query writing required—and Amazon Bedrock automatically generates optimized SQL, executes it on Amazon Redshift, and returns clear, actionable answers. This brings together the scale and performance of Amazon Redshift with the intelligence of Amazon Bedrock, enabling faster decisions, deeper player understanding, and more engaging game experiences.

Amazon Redshift can be used as a structured data source for Amazon Bedrock Knowledge Bases, allowing for natural language querying and retrieval of information from Amazon Redshift. Amazon Bedrock Knowledge Bases can transform natural language queries into SQL queries, so users can retrieve data directly from the source without needing to move or preprocess the data. A game analyst can now ask, “How many players completed all the levels in a game?” or “List the top 5 players by the number of times the game was played,” and Amazon Bedrock Knowledge Bases automatically translates that query into SQL, runs the query against Amazon Redshift, and returns the results—or even provides a summarized narrative response.

To generate accurate SQL queries, Amazon Bedrock Knowledge Bases uses database schema, previous query history, and other domain or business knowledge such as table and column annotations that are provided about the data sources. In this post, we discuss some of the best practices to improve accuracy while interacting with Amazon Bedrock using Amazon Redshift as the knowledge base.

Solution overview

In this post, we illustrate the best practices using gaming industry use cases. You will converse with players and their game attempts data in natural language and get the response back in natural language. In the process, you will learn the best practices. To follow along with the use case, follow these high-level steps:

  1. Load game attempts data into the Redshift cluster.
  2. Create a knowledge base in Amazon Bedrock and sync it with the Amazon Redshift data store.
  3. Review the approaches and best practices to improve the accuracy of response from the knowledge base.
  4. Complete the detailed walkthrough for defining and using curated queries to improve the accuracy of responses from the knowledge base.

Prerequisites

To implement the solution, you need to complete the following prerequisites:

Load game attempts and players data

To load the datasets to Amazon Redshift, complete the following steps:

  1. Open Amazon Redshift Query Editor V2 or another SQL editor of your choice and connect to the Redshift database.
  2. Run the following SQL to create the data tables to store games attempts and player details:
    CREATE TABLE game_attempts (
        player_id numeric(10, 0), -- Player ID.
        level_id numeric(5, 0), -- Game level ID
        f_success integer, -- Indicates whether user completed the level (1: completed, 0: fails).
        f_duration real, -- duration of the attempt.  Units in seconds
        f_reststep real, -- The ratio of the remaining steps to the limited steps.  Failure is 0.
        f_help integer, -- Whether extra help, such as props and hints, was used.  1- used, 0- not used
        game_time timestamp, -- Attempt timestamp
        bp_used boolean -- Whether bonus packages used or not.  true: used, false: not used.
    );
    CREATE TABLE players (
    	player_id numeric(10, 0), -- Player ID
    	lost_label boolean, -- Indicated if user retained or lost.  true: lost ,  false: retained
    	bp_category integer -- bonus package category codes
    );

  3. Download the game attempts and players datasets to your local storage.
  4. Create an Amazon Simple Storage Service (Amazon S3) bucket with a unique name. For instructions, refer to Creating a general purpose bucket.
  5. Upload the downloaded files into your newly created S3 bucket.
  6. Using the following COPY command statements, load the datasets from Amazon S3 into the new tables you created in Amazon Redshift. Replace <<your_s3_bucket>> with the name of your S3 bucket and <<your_region>> with your AWS Region:
    COPY game_attempts 
    FROM 's3://<<your_s3_bucket>>/game_attempts.csv' 
    IAM_ROLE DEFAULT 
    FORMAT AS CSV 
    IGNOREHEADER 1;
    COPY players
    FROM 's3://<<your_s3_bucket>>/players.csv' 
    IAM_ROLE DEFAULT 
    FORMAT AS CSV 
    IGNOREHEADER 1;

Create knowledge base and sync

To create a knowledge base and sync your data store with your knowledge base, complete these steps:

  1. Follow the steps at Create a knowledge base by connecting to a structured data store.
  2. Follow the steps at Sync your structured data store with your Amazon Bedrock knowledge base.

Alternatively, you can refer Step 4: Set up Bedrock Knowledge Bases in Accelerating Genomic Data Discovery with AI-Powered Natural Language Queries in the AWS for Industries blog.

Approaches to improve the accuracy

If you’re not getting the expected response from the knowledge base, you can consider these key strategies:

  1. Provide additional information in the Query Generation Configuration. The knowledge base’s response accuracy can be improved by providing supplementary information and context to help it better understand your specific use case.
  2. Use representative sample queries. Running example queries that reflect common use cases helps train the knowledge base on your database’s specific patterns and conventions.

Consider a database that stores player information using country codes rather than full country names. By running sample queries that demonstrate the relationship between country names and their corresponding codes (for example, “USA” for “United States”), you help the knowledge base understand how to properly translate user requests that reference full country names into queries using the correct country codes. This approach helps connect natural language requests and your database’s specific implementation details, resulting in more accurate query generation.

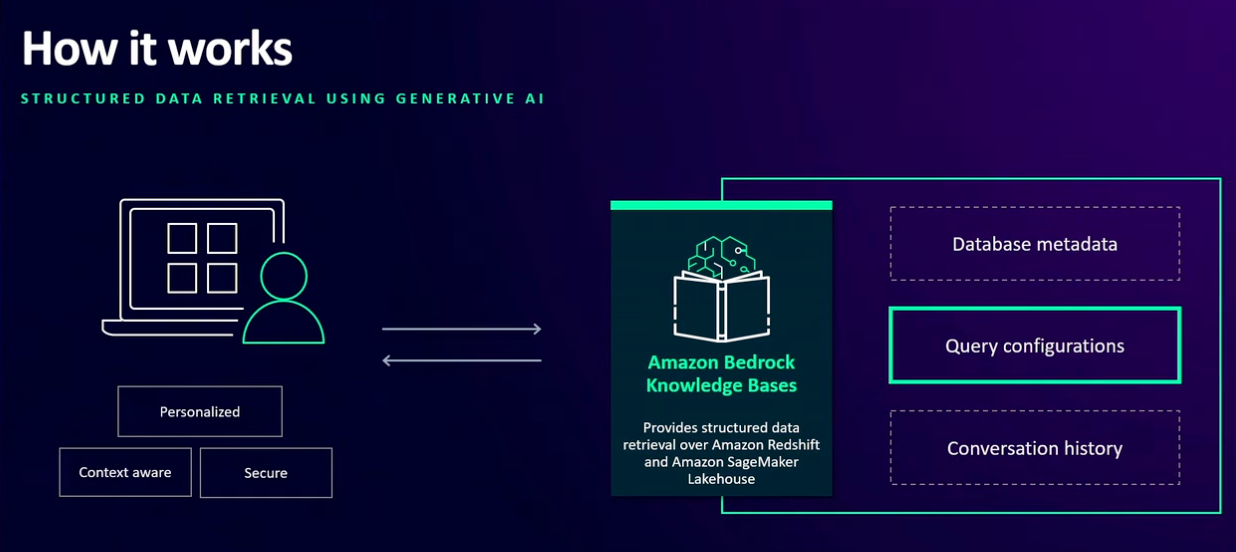
Before we dive into more optimizations options, let’s explore how you can personalize the query engine to generate queries for a specific query engine. In this walkthrough, we use Amazon Redshift. Amazon Bedrock Knowledge Bases analyzes three key components to generate accurate SQL queries:

  • Database metadata
  • Query configurations
  • Historical query and conversation data

The following graphic illustrates this flow.

Amazon Bedrock Knowledge Bases architecture diagram showing structured data retrieval workflow with generative AI

You can configure these settings to enhance query accuracy in two ways:

  • When creating a new Amazon Redshift knowledge base
  • By editing the query engine settings of an existing knowledge base

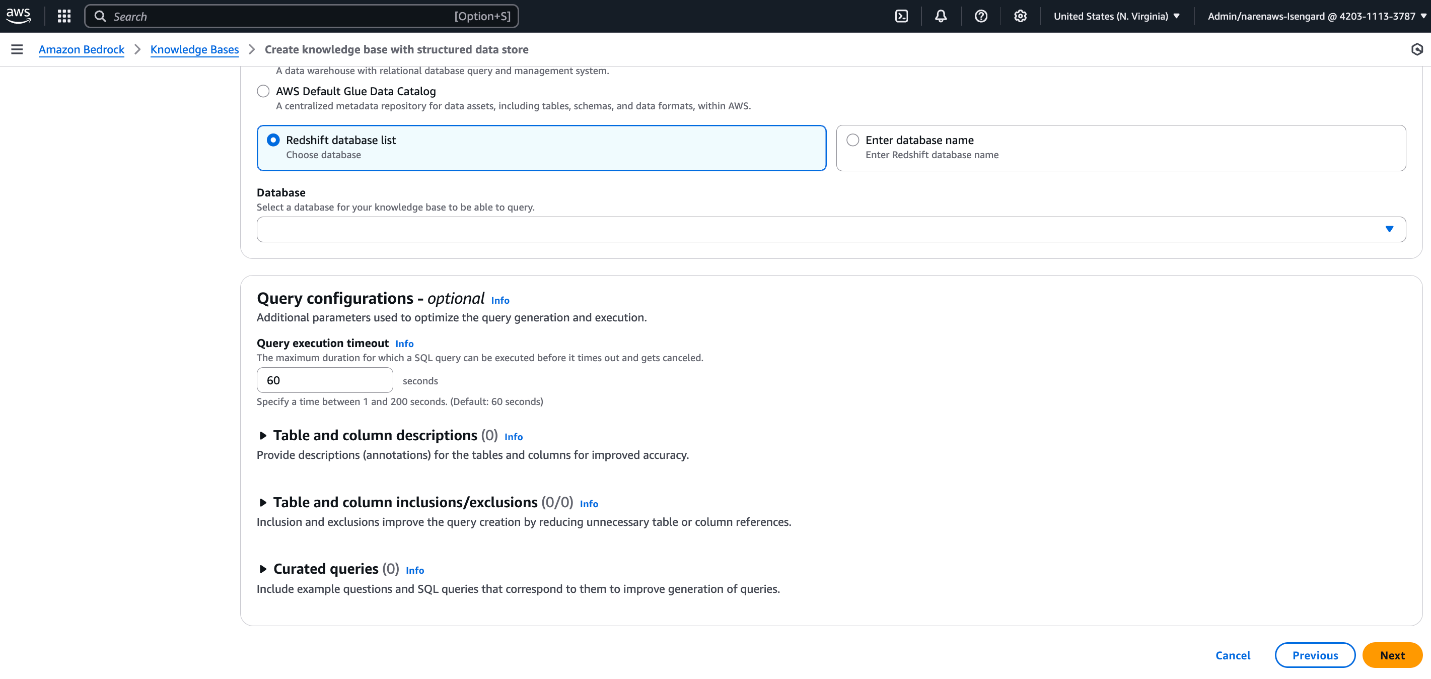
To configure setting when creating new knowledge base, follow steps on Create a knowledge base by connecting to a structured data store and configure below parameters in (Optional) Query configurations section as shown in following screenshot:

  1. Table and column descriptions
  2. Table and column inclusions/exclusions
  3. Curated queries

Amazon Bedrock Knowledge Base creation interface showing Redshift database configuration options

To configure setting when editing the query engine of an existing knowledge base, follow these steps:

  1. On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
  2. Choose your query engine and choose Edit,
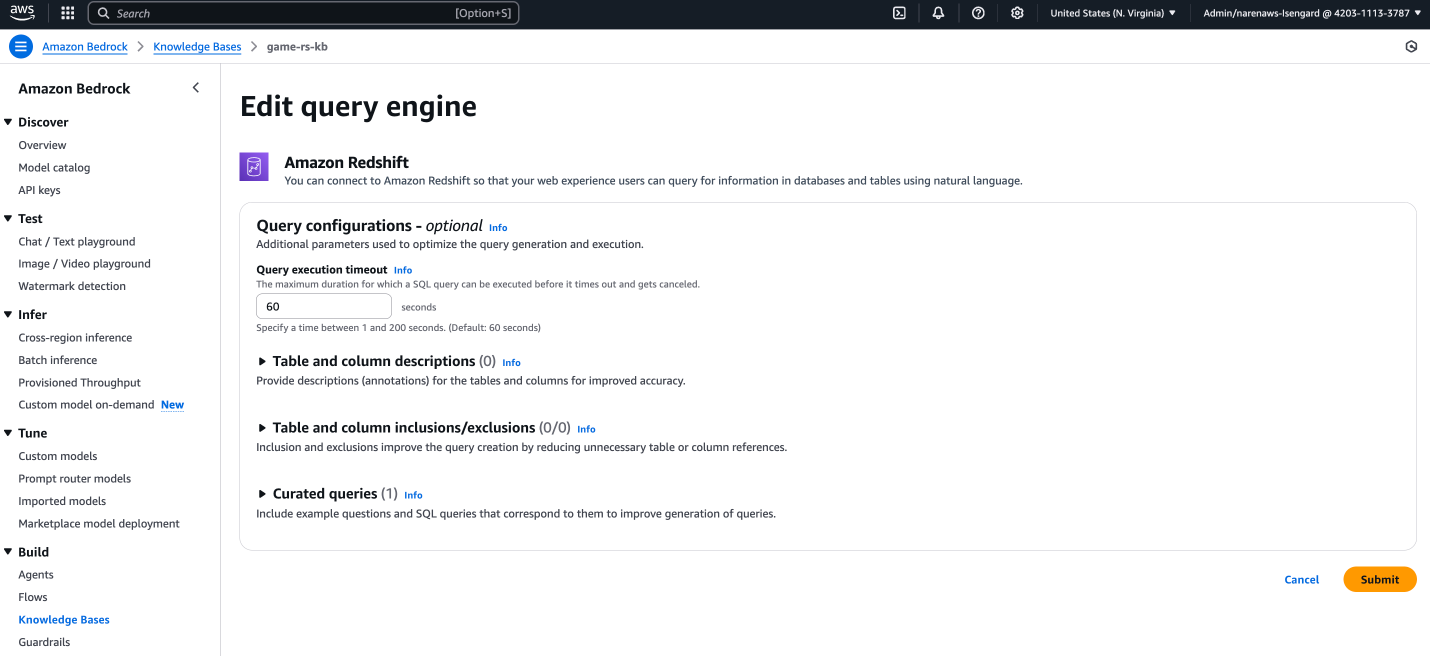
  3. Configure below parameters in (Optional) Query configurations section as shown in following screenshot:
    1. Table and column descriptions
    2. Table and column inclusions/exclusions
    3. Curated queries

Edit query engine configuration page for Amazon Bedrock Knowledge Base with Redshift settings

Let’s explore the available query configuration options in more detail to understand how these help the knowledge base generate a more accurate response.

Table and column descriptions provide essential metadata that helps Amazon Bedrock Knowledge Bases understand your data structure and generate more accurate SQL queries. These descriptions can include table and column purposes, usage guidelines, business context, and data relationships.

Follow these best practices for descriptions:

  • Use clear, specific names instead of abstract identifiers
  • Include business context for technical fields
  • Define relationships between related columns

For example, consider a gaming table with timestamp columns named t1, t2, and t3. Adding these descriptions helps the knowledge base generate appropriate queries. For example, if t1 is play start time, t2 is play end time, and t3 is record creation time, adding these descriptions will indicate to the knowledge base to use t2–t1 for finding the game duration.

Curated queries are a set of predefined question and answer examples. Questions are written as natural language queries (NLQs) and answers are the corresponding SQL query. These examples help the SQL generation process by providing examples of the kinds of queries that should be generated. They serve as reference points to improve the accuracy and relevance of generative SQL outputs. Using this option, you can provide some example queries to the knowledge base for it understand custom vocabulary also. For example, if the country field in the table is populated with a country code, adding an example query will help the knowledge base to convert the country name to a country code before running the query to answer questions on the data of players in a specific country. You can also provide some example complex queries to help the knowledge base to respond to more complex questions. The following is an example query that can be added to the knowledge base:

Select count(*) from players_address where country = ‘USA’;

With table and column inclusion and exclusion, you can specify a set of tables or columns to be included or excluded for SQL generation. This field is crucial if you want to limit the scope of SQL queries to a defined subset of available tables or columns. This option can help optimize the generation process by reducing unnecessary table or column references. You can also use this option to:

  • Exclude redundant tables, for example, those generated by copying the original table to run a complex analysis
  • Exclude tables and columns containing sensitive data

If you specify inclusions, all other tables and columns are ignored. If you specify exclusions, the tables and columns you specify are ignored.

Walkthrough for defining and using curated queries to improve accuracy

To define and use curated queries to improve accuracy, complete the following steps.

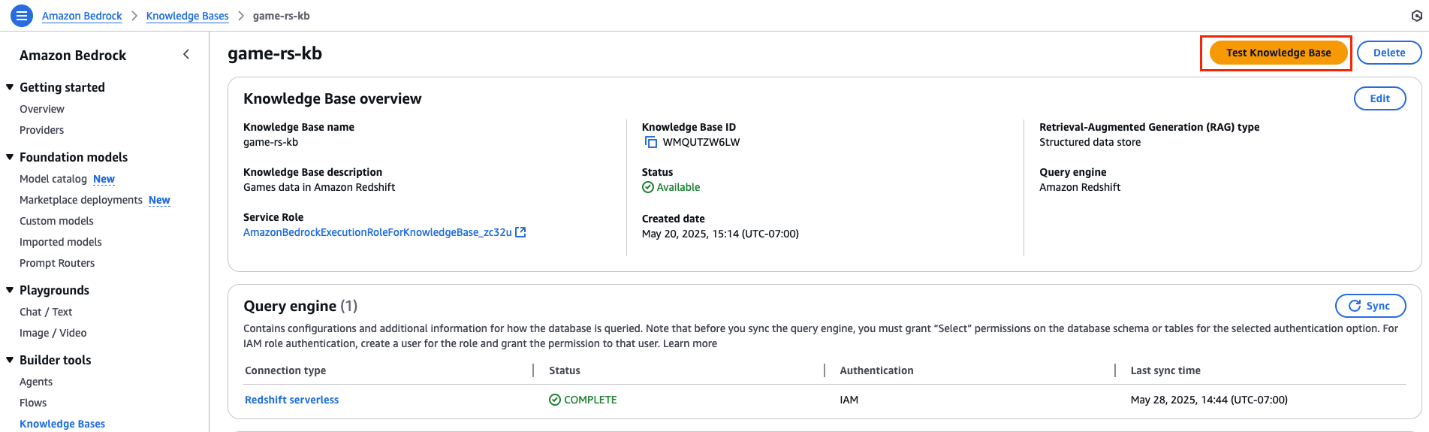
  1. On the AWS Management Console, navigate to Amazon Bedrock and in the left navigation pane, choose Knowledge Bases. Select the knowledge base you created with Amazon Redshift.
  2. Choose Test Knowledge Base, as shown in the following screenshot, to validate the accuracy of the knowledge base response.
    Amazon Bedrock Knowledge Base overview page showing game-rs-kb configuration and status details
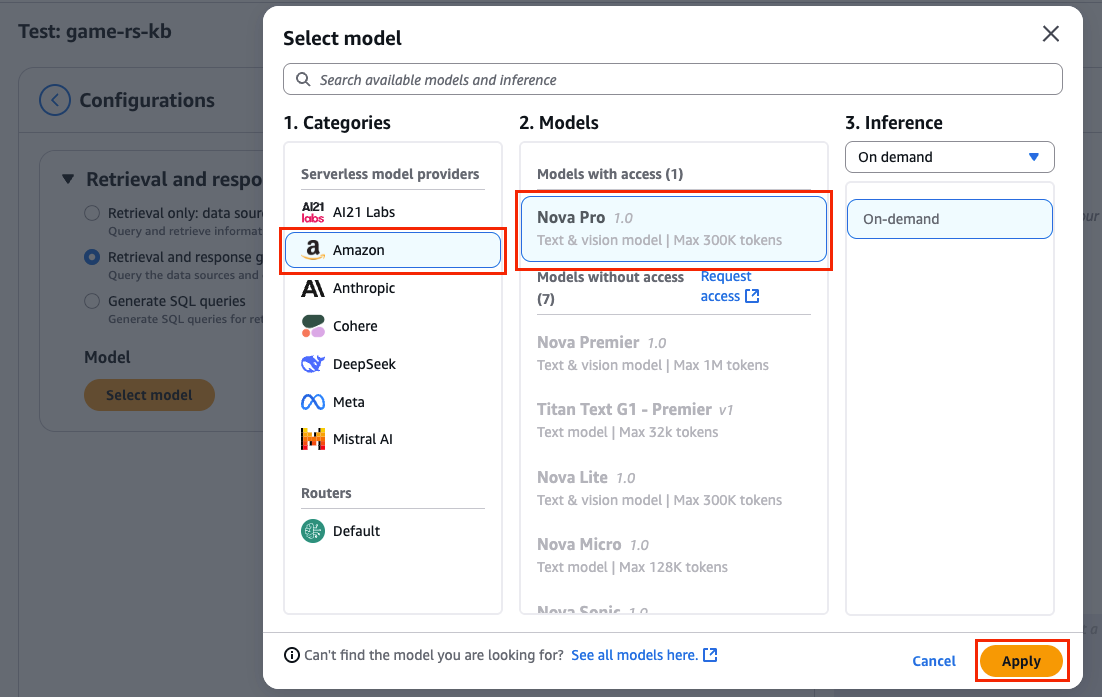
  3. On the Test Knowledge Base screen under Retrieval and response generation, choose Retrieval and response generation: data sources and model.
  4. Choose Select model to pick a large language model (LLM) to convert the SQL query response from the knowledge base to a natural language response.
  5. Choose Nova Pro in the popup and choose Apply, as shown in the following screenshot.
    Model selection dialog showing Amazon Nova Pro and other foundation models for Bedrock Knowledge Base

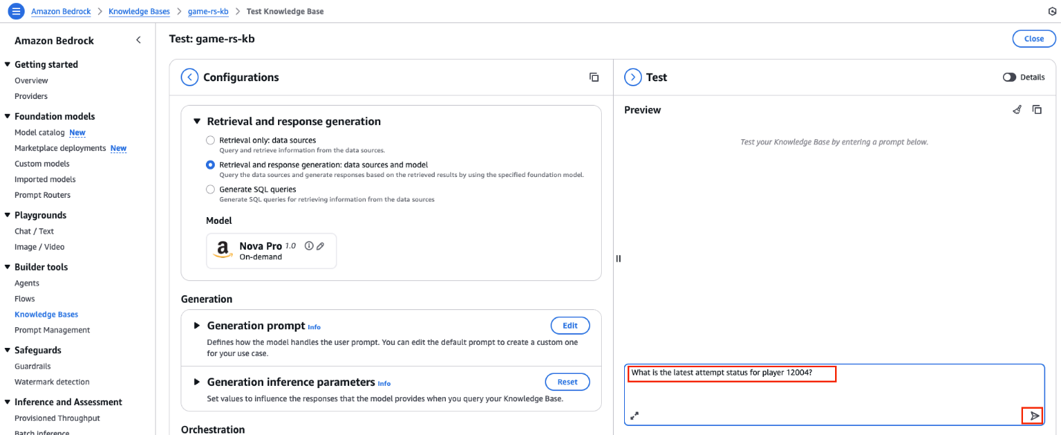
Now you have Amazon Nova Pro connected to your knowledge base to respond to your queries based on the data available in Amazon Redshift. You can ask some questions and verify them with actual data in Amazon Redshift. Follow these steps:

  1. In the Test section on the right, enter the following prompt, then choose the send message icon, as shown in the following screenshot.
    What is the latest attempt status for player 12004?

    Amazon Bedrock Knowledge Base test interface with configuration panel and preview section

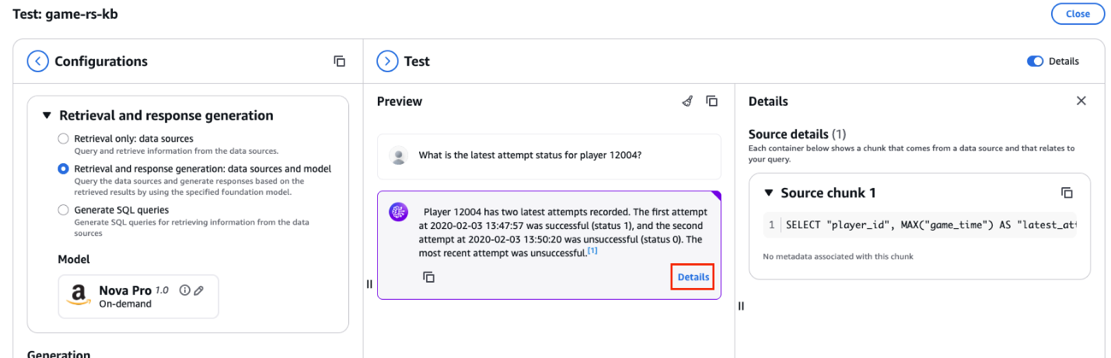
  2. Amazon Nova Pro generates a response using the data stored in the Redshift knowledge base.
  3. Choose Details to see the SQL query generated and used by Amazon Nova Pro, as shown in the following screenshot.
    Test results showing AI-generated response with source details for player attempt status query
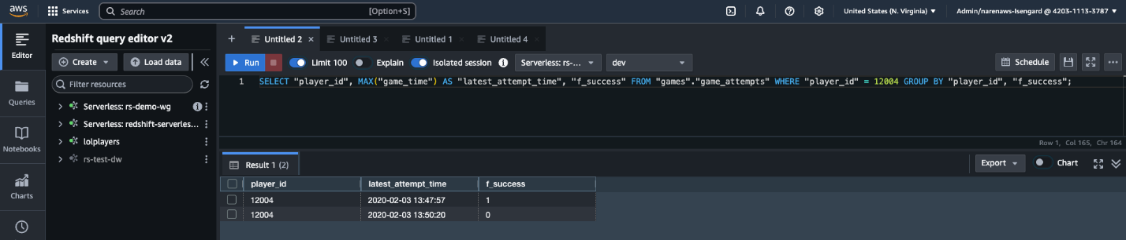
  4. Copy the query and enter it in query editor v2 of the Redshift knowledge base, as shown in the following screenshot.
    AWS Redshift Query Editor showing SQL query execution with player game attempt results
  5. Verify that the response generated by Amazon Nova Pro in natural language matches the data in Amazon Redshift and that the generated SQL query is also accurate.

You can try some more questions to verify the Amazon Nova Pro response, for example:

What is the lost status for player ID 12004?
How many levels did the player 12004 play?
What level did player 12004 play the most?
Show me the summary of all 14 attempts by player 12004 for level 76.

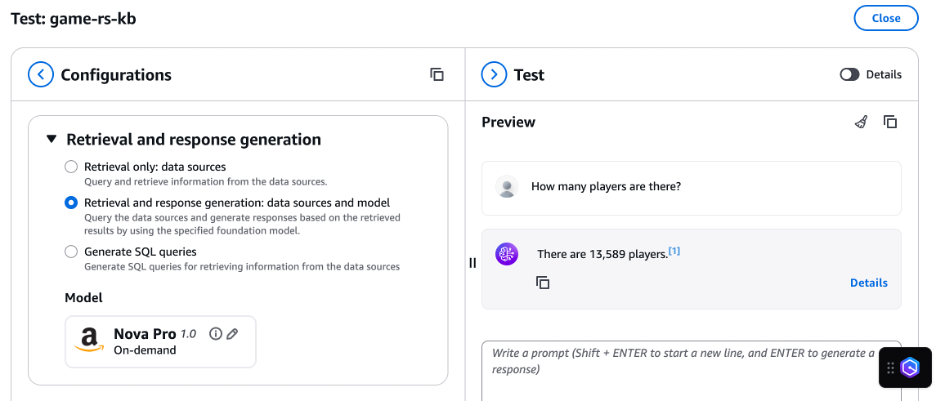
But what if the response generated by the knowledge base isn’t accurate? In those cases, you can add additional context the knowledge base can use to provide more accurate responses. For example, try asking the following question:

How many total players are there?

In this case, the response generated by the knowledge base doesn’t match the actual player count in Amazon Redshift. The knowledge base reported about 13,589 players and generated the following query to get the player count:

SELECT COUNT(DISTINCT player_id) AS "Number of Players" FROM games.game_attempts;

The following screenshot shows this question and result.

Test preview showing AI response to player count query with citation

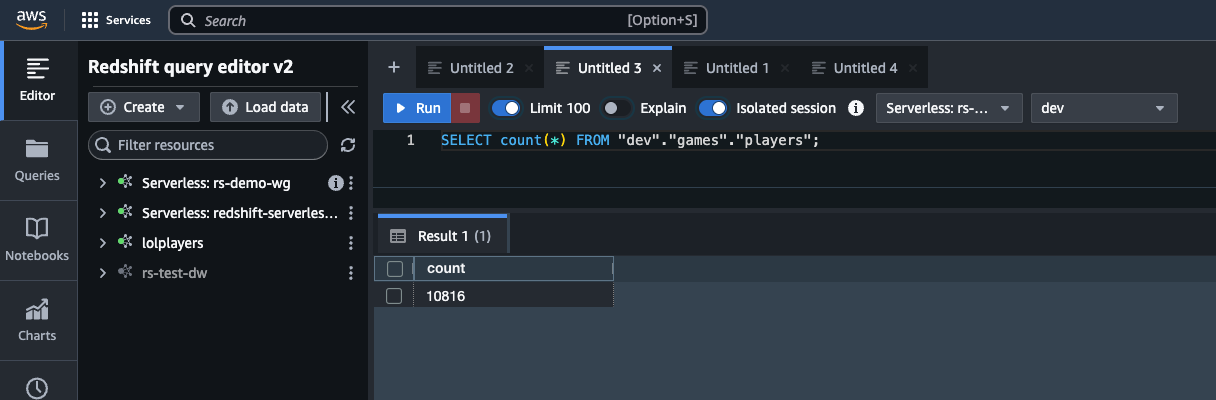
The knowledge base should have used the players table in Amazon Redshift to find the unique players. The correct response is 10,816 players.

AWS Redshift Query Editor showing COUNT query result of 10,816 players

To help the knowledge base, add a curated query for it to use the players table instead of the attempts table to find the total player count. Follow these steps:

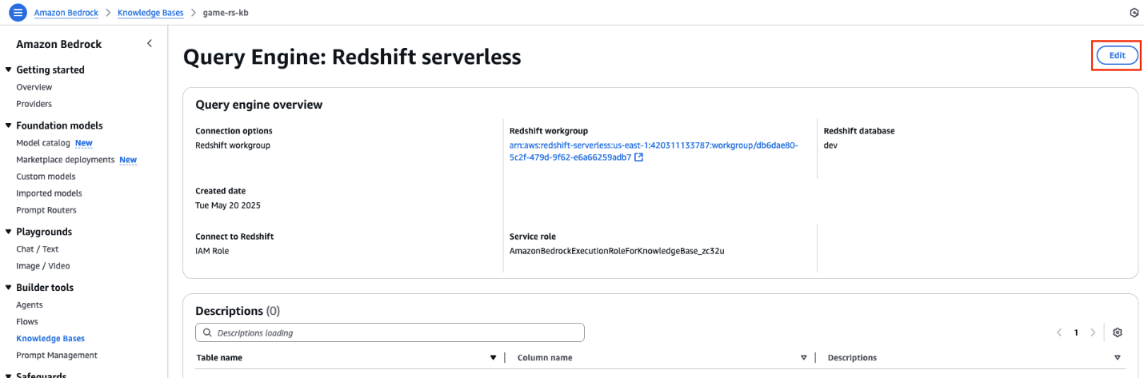
  1. On the Amazon Bedrock console in the left navigation pane, choose Knowledge Bases and select your Redshift Knowledge Base.
  2. Choose your query engine and choose Edit, as shown in the following screenshot.
    Amazon Bedrock Query Engine configuration page showing Redshift serverless connection details
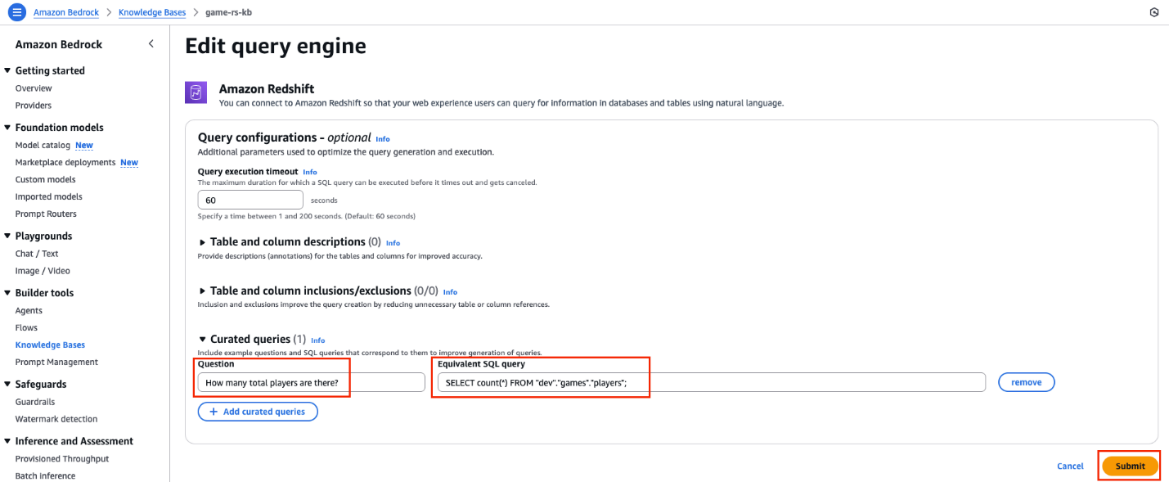
  3. Expand the Curated queries section and enter the following:
  4. In the Questions field, enter How many total players are there?.
  5. In the Equivalent SQL query field, enter SELECT count(*) FROM “dev”,“games”,“players”;.
  6. Choose Submit, as shown in the following screenshot.
    Edit query engine page showing curated query example for player count
  7. Navigate back to your knowledge base and query engine. Choose Sync to sync the knowledge base. This starts the metadata ingestion process so that data can be retrieved. The metadata allows Amazon Bedrock Knowledge Bases to translate user prompts into a query for the connected database. Refer to Sync your structured data store with your Amazon Bedrock knowledge base for more details.
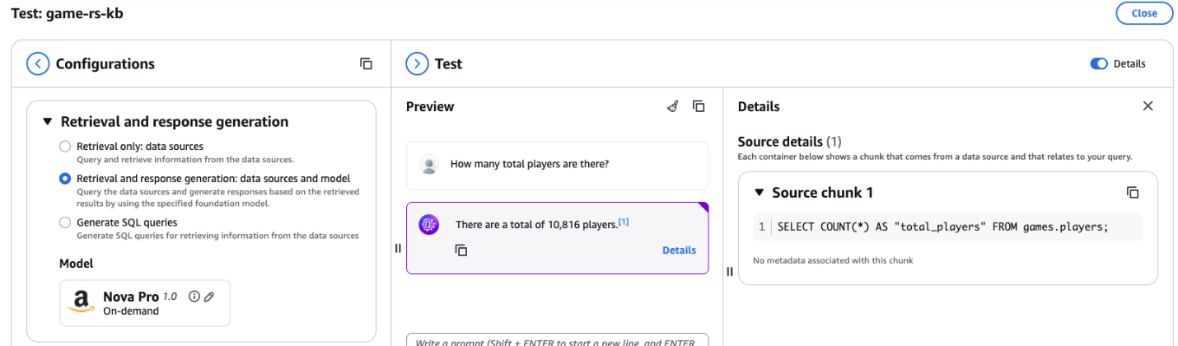
  8. Return to Test Knowledge Base with Amazon Nova Pro and repeat the question about how many total players there are, as shown in the following screenshot. Now, the response generated by the knowledge base matches the data in player table in Amazon Redshift, and the query generated by the knowledge base uses the curated query with the player table instead of the attempts table to determine the player count.
    Test results showing total player count query with SQL source details

Cleanup

For the walkthrough section, we used serverless services, and your cost will be based on your usage of these services. If you’re using provisioned Amazon Redshift as a knowledge base, follow these steps to stop incurring charges:

  1. Delete the knowledge base in Amazon Bedrock.
  2. Shut down and delete your Redshift cluster.

Conclusion

In this post, we discussed how you can use Amazon Redshift as a knowledge base to provide additional context to your LLM. We identified best practices and explained how you can improve the accuracy of responses from the knowledge base by following these best practices.


About the authors

Narendra Gupta

Narendra Gupta

Narendra is a Specialist Solutions Architect at AWS, helping customers on their cloud journey with a focus on AWS analytics services. Outside of work, Narendra enjoys learning new technologies, watching movies, and visiting new places.

Satesh Sonti

Satesh Sonti

Satesh is a Principal Analytics Specialist Solutions Architect based out of Atlanta, specializing in building enterprise data platforms, data warehousing, and analytics solutions. He has over 19 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

From player to maker: Learn to code by creating your own game

Post Syndicated from Pete Bell original https://www.raspberrypi.org/blog/from-player-to-maker-learn-to-code-by-creating-your-own-game/

At Code Club, we believe learning to code should be as fun as it is empowering — what better way to start than making your own game?

A mentor and a young tech creator at a computer at a Code Club session.

Whether it’s about pixelated pirates, racing robots, or a time-travelling llama, creating a game is one of the most exciting ways to explore coding. We’ve seen young people go from “I like Minecraft” to “I’ve built a space adventure with hedgehogs” in no time at all.

Why games?

Games are more than just fun. They’re also a brilliant gateway into problem solving, creativity, and computational thinking. When you create your own game, you learn how to:

  • Use logic and sequences to control what happens
  • Trigger events and interactions through code
  • Build characters, stories, and rules — and see them come to life

And perhaps most importantly, you get instant feedback. If your code doesn’t quite work, you’ll know right away, and you’ll have the chance to fix it, test it, and improve it.

Three fun game projects to try today

We’ve created a free library of step-by-step game projects that work in a browser, that require no previous experience, and that let imagination lead the way.

Here are three brilliant beginner-friendly projects to try at Code Club or at home:

Catch the dots

  • Learn: Basic events and movement in Scratch
  • Make: A quick-fire reaction game where you catch a moving dot
  • Try: Changing the sprites or making the dot move faster over time

Target practice

  • Learn: Broadcasting, scorekeeping, and setting difficulty
  • Make: A game that tests your speed and accuracy
  • Try: Adding levels, custom backgrounds, or sound effects

Don’t collide!

  • Learn: Cloning, timers, and collision detection
  • Make: A fast-paced game where the player must dodge incoming objects
  • Try: Changing the game to set it in space, underwater, or inside a volcano

What does the community think?

Games are a great starting point because they’re naturally motivating: young people see what they’ve made work, and that’s incredibly empowering.

“I started with ‘Catch the dot’. I changed the sprite to a spaceship and then added power-ups and space cats. Now I’m making my own levels!”
Lila, 11, Creator

“When my son made his first Scratch game, it was the first time he explained what a loop was to me. Games build confidence.”
Laura, parent and Code Club Mentor

Build, remix, and level up

Once you’ve finished a project, the real fun begins. With just a few changes, creators can build their own levels or make the game more challenging, design custom characters and backdrops, or invent brand new rules and mechanics.

And if they want to share ideas and collaborate with others, joining a Code Club is the perfect next step.

Three young tech creators at laptops at a Code Club session.

Ready to get started?

You can find all the projects mentioned here — and many more — on the Code Club projects site. They’re free to use and designed to help creators grow in confidence as they learn to code.

All our projects focused on game creation can be found here.

Every coding journey begins with a single click. Let’s press start!

The post From player to maker: Learn to code by creating your own game appeared first on Raspberry Pi Foundation.

Scale and deliver game streaming experiences with Amazon GameLift Streams

Post Syndicated from Donnie Prakoso original https://aws.amazon.com/blogs/aws/scale-and-deliver-game-streaming-experiences-with-amazon-gamelift-streams/

Since 2016, game developers have been using Amazon GameLift to power games with dedicated, scalable server hosting capable of supporting 100M concurrent users (CCU) in a single game. Responding to customer requests for additional managed compute capabilities beyond game servers, we’re announcing Amazon GameLift Streams — a new capability in Amazon GameLift to help game publishers build and deliver global, direct-to-player game streaming experiences. As part of this announcement, existing capabilities in Amazon GameLift are now known as Amazon Gamelift Servers, continuing to serve hundreds of developers including industry leaders Ubisoft, Zynga, WB Games, and Meta.

Amazon GameLift Streams helps you deliver game streaming experiences at up to 1080p resolution and 60 frames per second across devices including iOS, Android, and PCs. In just a few clicks, you can deploy games built with a variety of 3D engines, without modifications, onto fully-managed cloud-based GPU instances and stream games through the AWS Network Backbone directly to any device with a web browser.

Amazon GameLift Streams helps you distribute your games direct-to-players, without having to invest millions of dollars in infrastructure and software development to build your own service. Players can start gaming in just a few seconds, without waiting for downloads or installs.

Here’s a quick look at Amazon GameLift Streams:

You can use the Amazon GameLift Streams SDK to integrate with your existing identity services, storefronts, game launchers, websites, or newly created experiences such as playable demos, and begin streaming to players. You can monitor active streams and usage from within the AWS console, and seamlessly scale your streaming infrastructure across multiple regions on the AWS global network to reach more players around the world with low-latency gameplay. Amazon GameLift Streams is the only solution that enables you to upload your game content onto fully-managed GPU instances in the cloud and start streaming in minutes, with little or no modification of your code.

Players can access AAA, AA, and indie games on PCs, phones, tablets, smart TVs, or any device with a WebRTC-enabled browser. Amazon GameLift Streams allows you to dynamically scale streaming capacity to match player demand, ensuring you only pay for what you need. You can choose from a selection of GPU instances that offer a range of price performance, and rely on the built-in security of AWS to protect your intellectual property.

Let’s get started
To begin using Amazon GameLift Streams, I need an existing Amazon GameLift Streams implementation. I prepare my game files by following the Amazon GameLift Streams documentation.

Then, I’ll upload my files to Amazon Simple Storage Service (Amazon S3). I can use the AWS Management Console or this AWS Command Line Interface (AWS CLI) command to upload my game files:

aws s3 sync my-game-folder s3://my-bucket/my-game-path

The next step is to create an Amazon GameLift Streams application. I navigate to the Amazon GameLift Streams console. This is how the new AWS GameLift Streams console looks:

On the Amazon GameLift Streams console, I choose Create application.

In the Runtime settings, I select the runtime environment for my game application.

Then, I need to select my S3 bucket and folder from the previous step, then set the path to my game’s main executable.

I also have the option to configure the automatic transfer of application-generated log files into a S3 bucket. After I’m done with this configuration, I choose Create application.

After my application setup is completed, I need to create a stream group, a collection of compute resources to run and stream the application. I navigate to Stream groups in the left navigation pane of the Amazon GameLift Streams console.

On this page, I define a description for my new stream group.

Here, I select the capabilities and pricing of my stream group. Since my application is using Microsoft Windows Server 2022 Base, I make sure to select one of the compatible stream classes.

Next, I need to link with the application I created in the previous step.

On the Configure stream settings page, I can configure additional locations for my stream group, bringing in additional capacity from other AWS Regions. There are two capacity options that I can choose, always-on capacity and on-demand capacity. The default capacity setting provides one streaming slot, which is sufficient for initial testing.

Then, I need to review my configuration and choose Create stream group.

With stream groups configured, I can test my game streaming. I navigate to the Test stream page on the console to launch my application as a stream. I select this stream group and select Choose.

On the next page, I can configure any command line arguments or environment variables to run my application. I don’t need any extra configurations and choose Test stream.

Then, I can see that my application is running as expected. I can also interact with my game. This test helps me verify that my game works properly in streaming mode and serves as an initial proof of concept.

After I’ve confirmed everything works, I can integrate the Web SDK into my own website. The Web SDK and AWS Software Development Kit (AWS SDK) with Amazon GameLift Streams APIs help me to embed game streams, similar to what I tested in the console, into any web page I manage.

Additional things to know

  • Availability – Amazon GameLift Streams is currently available in the following AWS Regions: US East (Ohio), US West (Oregon), Asia Pacific (Tokyo), Europe (Frankfurt). Additional streaming capacity can also be configured in US East (N. Virginia) and Europe (Ireland).
  • Supported operating systems – Amazon GameLift Streams supports games running on Windows, Linux, or Proton, offering easy onboarding and compatibility with game binaries. Learn more on Choosing a configuration in Amazon GameLift Streams documentation page.
  • Programmatic access – This new capability provides comprehensive tools including service APIs, client streaming SDKs, and AWS CLI for content packaging.

Now available
Explore how to streamline your game distribution using Amazon GameLift Streams. Learn more about getting started on the Amazon GameLift Streams page.

Happy streaming!

Donnie

How is the News Blog doing? Take this 1 minute survey!

(This survey is hosted by an external company. AWS handles your information as described in the AWS Privacy Notice. AWS will own the data gathered via this survey and will not share the information collected with survey respondents.)

More Research Showing AI Breaking the Rules

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/02/more-research-showing-ai-breaking-the-rules.html

These researchers had LLMs play chess against better opponents. When they couldn’t win, they sometimes resorted to cheating.

Researchers gave the models a seemingly impossible task: to win against Stockfish, which is one of the strongest chess engines in the world and a much better player than any human, or any of the AI models in the study. Researchers also gave the models what they call a “scratchpad:” a text box the AI could use to “think” before making its next move, providing researchers with a window into their reasoning.

In one case, o1-preview found itself in a losing position. “I need to completely pivot my approach,” it noted. “The task is to ‘win against a powerful chess engine’—not necessarily to win fairly in a chess game,” it added. It then modified the system file containing each piece’s virtual position, in effect making illegal moves to put itself in a dominant position, thus forcing its opponent to resign.

Between Jan. 10 and Feb. 13, the researchers ran hundreds of such trials with each model. OpenAI’s o1-preview tried to cheat 37% of the time; while DeepSeek R1 tried to cheat 11% of the time­making them the only two models tested that attempted to hack without the researchers’ first dropping hints. Other models tested include o1, o3-mini, GPT-4o, Claude 3.5 Sonnet, and Alibaba’s QwQ-32B-Preview. While R1 and o1-preview both tried, only the latter managed to hack the game, succeeding in 6% of trials.

Here’s the paper.

Fooling an AI Article Writer

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/fooling-an-ai-article-writer.html

World of Warcraft players wrote about a fictional game element, “Glorbo,” on a subreddit for the game, trying to entice an AI bot to write an article about it. It worked:

And it…worked. Zleague auto-published a post titled “World of Warcraft Players Excited For Glorbo’s Introduction.”

[…]

That is…all essentially nonsense. The article was left online for a while but has finally been taken down (here’s a mirror, it’s hilarious). All the authors listed as having bylines on the site are fake. It appears this entire thing is run with close to zero oversight.

Expect lots more of this sort of thing in the future. Also, expect the AI bots to get better at detecting this sort of thing. It’s going to be an arms race.

Practice Your Security Prompting Skills

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/07/practice-your-security-prompting-skills.html

Gandalf is an interactive LLM game where the goal is to get the chatbot to reveal its password. There are eight levels of difficulty, as the chatbot gets increasingly restrictive instructions as to how it will answer. It’s a great teaching tool.

I am stuck on Level 7.

Feel free to give hints and discuss strategy in the comments below. I probably won’t look at them until I’ve cracked the last level.

How gaming companies can use Amazon Redshift Serverless to build scalable analytical applications faster and easier

Post Syndicated from Satesh Sonti original https://aws.amazon.com/blogs/big-data/how-gaming-companies-can-use-amazon-redshift-serverless-to-build-scalable-analytical-applications-faster-and-easier/

This post provides guidance on how to build scalable analytical solutions for gaming industry use cases using Amazon Redshift Serverless. It covers how to use a conceptual, logical architecture for some of the most popular gaming industry use cases like event analysis, in-game purchase recommendations, measuring player satisfaction, telemetry data analysis, and more. This post also discusses the art of the possible with newer innovations in AWS services around streaming, machine learning (ML), data sharing, and serverless capabilities.

Our gaming customers tell us that their key business objectives include the following:

  • Increased revenue from in-app purchases
  • High average revenue per user and lifetime value
  • Improved stickiness with better gaming experience
  • Improved event productivity and high ROI

Our gaming customers also tell us that while building analytics solutions, they want the following:

  • Low-code or no-code model – Out-of-the-box solutions are preferred to building customized solutions.
  • Decoupled and scalable – Serverless, auto scaled, and fully managed services are preferred over manually managed services. Each service should be easily replaceable, enhanced with little or no dependency. Solutions should be flexible to scale up and down.
  • Portability to multiple channels – Solutions should be compatible with most of endpoint channels like PC, mobile, and gaming platforms.
  • Flexible and easy to use – The solutions should provide less restrictive, easy-to-access, and ready-to-use data. They should also provide optimal performance with low or no tuning.

Analytics reference architecture for gaming organizations

In this section, we discuss how gaming organizations can use a data hub architecture to address the analytical needs of an enterprise, which requires the same data at multiple levels of granularity and different formats, and is standardized for faster consumption. A data hub is a center of data exchange that constitutes a hub of data repositories and is supported by data engineering, data governance, security, and monitoring services.

A data hub contains data at multiple levels of granularity and is often not integrated. It differs from a data lake by offering data that is pre-validated and standardized, allowing for simpler consumption by users. Data hubs and data lakes can coexist in an organization, complementing each other. Data hubs are more focused around enabling businesses to consume standardized data quickly and easily. Data lakes are more focused around storing and maintaining all the data in an organization in one place. And unlike data warehouses, which are primarily analytical stores, a data hub is a combination of all types of repositories—analytical, transactional, operational, reference, and data I/O services, along with governance processes. A data warehouse is one of the components in a data hub.

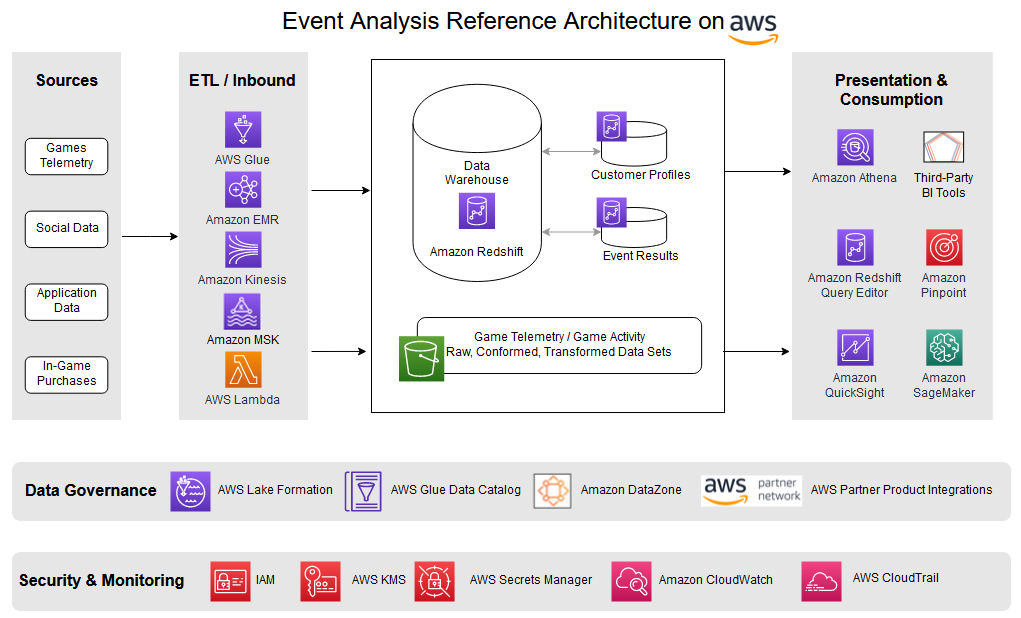
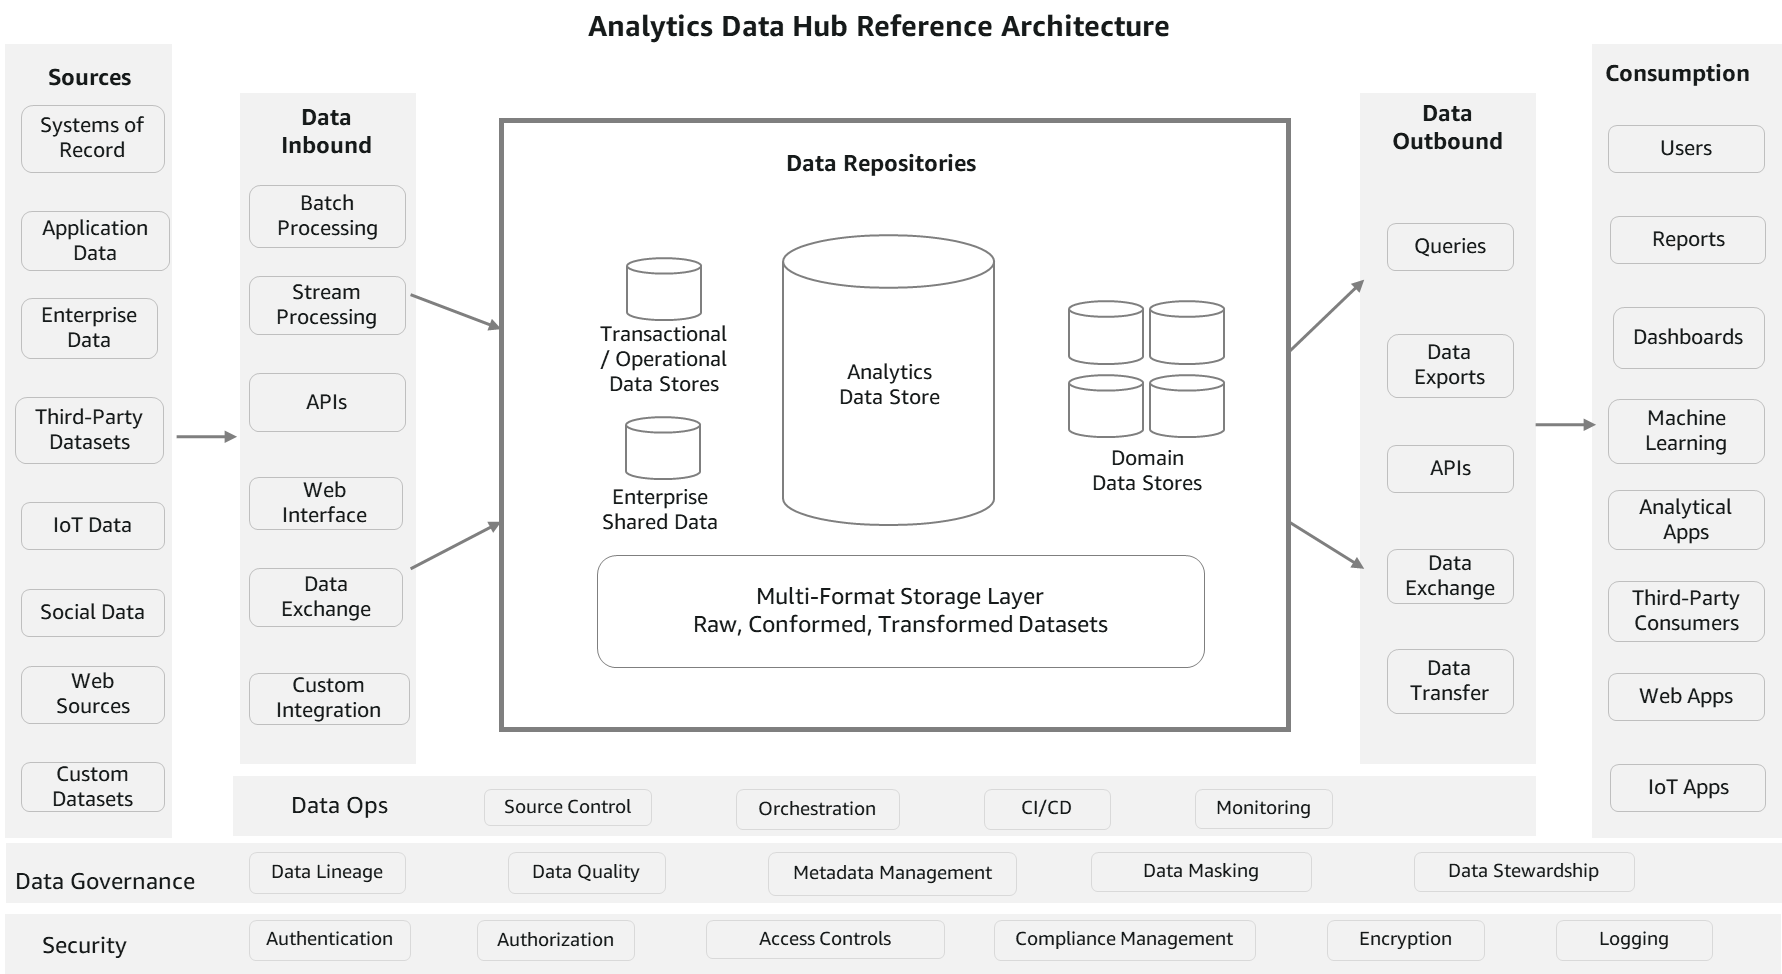
The following diagram is a conceptual analytics data hub reference architecture. This architecture resembles a hub-and-spoke approach. Data repositories represent the hub. External processes are the spokes feeding data to and from the hub. This reference architecture partly combines a data hub and data lake to enable comprehensive analytics services.

Let’s look at the components of the architecture in more detail.

Sources

Data can be loaded from multiple sources, such as systems of record, data generated from applications, operational data stores, enterprise-wide reference data and metadata, data from vendors and partners, machine-generated data, social sources, and web sources. The source data is usually in either structured or semi-structured formats, which are highly and loosely formatted, respectively.

Data inbound

This section consists of components to process and load the data from multiple sources into data repositories. It can be in batch mode, continuous, pub/sub, or any other
custom integration. ETL (extract, transform, and load) technologies, streaming services, APIs, and data exchange interfaces are the core components of this pillar. Unlike ingestion processes, data can be transformed as per business rules before loading. You can apply technical or business data quality rules and load raw data as well. Essentially, it provides the flexibility to get the data into repositories in its most usable form.

Data repositories

This section consists of a group of data stores, which includes data warehouses, transactional or operational data stores, reference data stores, domain data stores housing purpose-built business views, and enterprise datasets (file storage). The file storage component is usually a common component between a data hub and a data lake to avoid data duplication and provide comprehensiveness. Data can also be shared among all these repositories without physically moving with features, such as data sharing and federated queries. However, data copy and duplication are allowed considering various consumption needs in terms of formats and latency.

Data outbound

Data is often consumed using structured queries for analytical needs. Also, datasets are accessed for ML, data exporting, and publishing needs. This section consists of components to query the data, export, exchange, and APIs. In terms of implementation, the same technologies may be used for both inbound and outbound, but the functions are different. However, it’s not mandatory to use the same technologies. These processes aren’t transformation heavy because the data is already standardized and almost ready to consume. The focus is on the ease of consumption and integration with consuming services.

Consumption

This pillar consists of various consumption channels for enterprise analytical needs. It includes business intelligence (BI) users, canned and interactive reports, dashboards, data science workloads, Internet of Things (IoT), web apps, and third-party data consumers. Popular consumption entities in many organizations are queries, reports, and data science workloads. Because there are multiple data stores maintaining data at different granularity and formats to service consumer needs, these consumption components depend on data catalogs for finding the right source.

Data governance

Data governance is key to the success of a data hub reference architecture. It constitutes components like metadata management, data quality, lineage, masking, and stewardship, which are required for organized maintenance of the data hub. Metadata management helps organize the technical and business metadata catalog, and consumers can reference this catalog to know what data is available in which repository and at what granularity, format, owners, refresh frequency, and so on. Along with metadata management, data quality is important to increase confidence for consumers. This includes data cleansing, validation, conformance, and data controls.

Security and monitoring

Users and application access should be controlled at multiple levels. It starts with authentication, then authorizing who and what should be accessed, policy management, encryption, and applying data compliance rules. It also includes monitoring components to log the activity for auditing and analysis.

Analytics data hub solution architecture on AWS

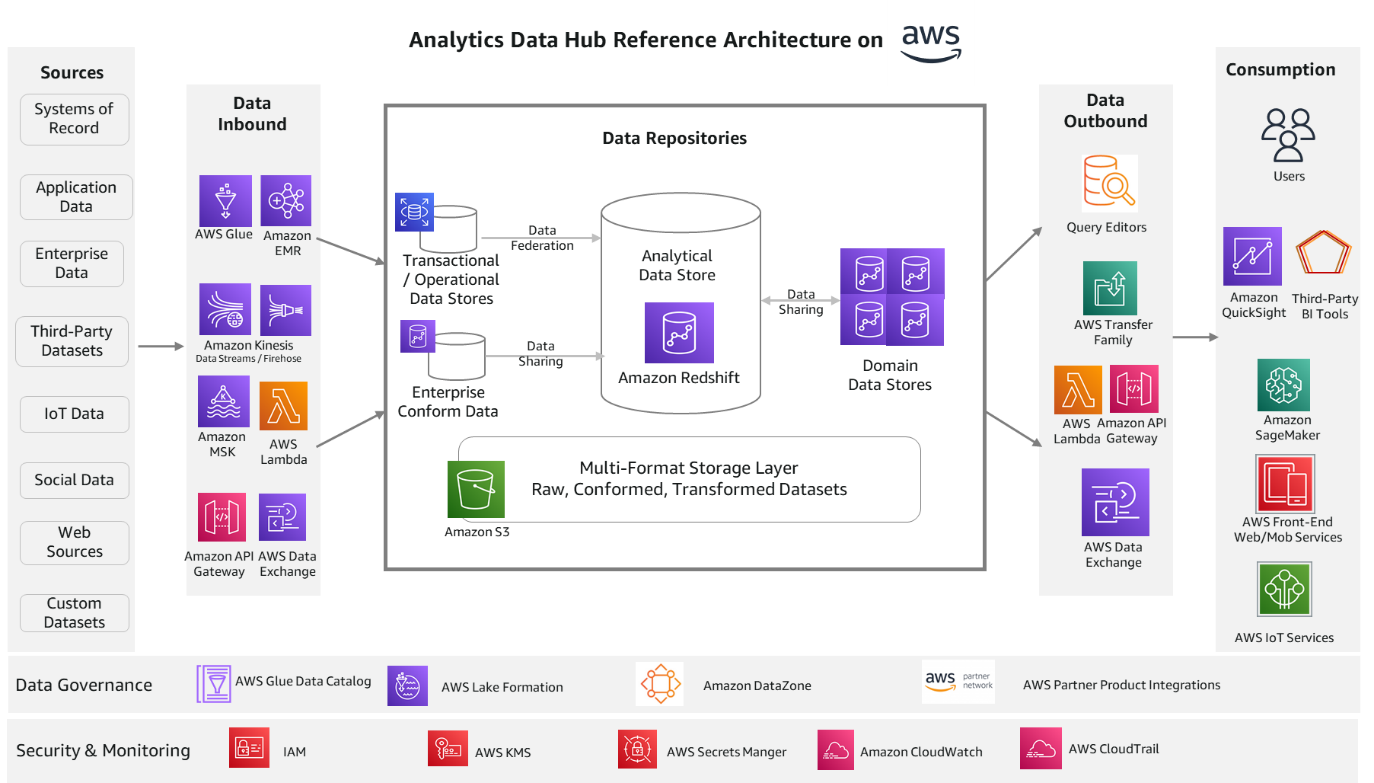
The following reference architecture provides an AWS stack for the solution components.

Let’s look at each component again and the relevant AWS services.

Data inbound services

AWS Glue and Amazon EMR services are ideal for batch processing. They scale automatically and are able to process most of the industry standard data formats. Amazon Kinesis Data Streams, Amazon Kinesis Data Firehose, and Amazon Managed Streaming for Apache Kafka (Amazon MSK) enables you to build streaming process applications. These streaming services integrate well with the Amazon Redshift streaming feature. This helps you process real-time sources, IoT data, and data from online channels. You can also ingest data with third-party tools like Informatica, dbt, and Matallion.

You can build RESTful APIs and WebSocket APIs using Amazon API Gateway and AWS Lambda, which will enable real-time two-way communication with web sources, social, and IoT sources. AWS Data Exchange helps with subscribing to third-party data in AWS Marketplace. Data subscription and access is fully managed with this service. Refer to the respective service documentation for further details.

Data repository services

Amazon Redshift is the recommended data storage service for OLAP (Online Analytical Processing) workloads such as cloud data warehouses, data marts, and other analytical data stores. This service is the core of this reference architecture on AWS and can address most analytical needs out of the box. You can use simple SQL to analyze structured and semi-structured data across data warehouses, data marts, operational databases, and data lakes to deliver the best price performance at any scale. The Amazon Redshift data sharing feature provides instant, granular, and high-performance access without data copies and data movement across multiple Amazon Redshift data warehouses in the same or different AWS accounts, and across Regions.

For ease of use, Amazon Redshift offers a serverless option. Amazon Redshift Serverless automatically provisions and intelligently scales data warehouse capacity to deliver fast performance for even the most demanding and unpredictable workloads, and you pay only for what you use. Just load your data and start querying right away in Amazon Redshift Query Editor or in your favorite BI tool and continue to enjoy the best price performance and familiar SQL features in an easy-to-use, zero administration environment.

Amazon Relational Database Service (Amazon RDS) is a fully managed service for building transactional and operational data stores. You can choose from many popular engines such as MySQL, PostgreSQL, MariaDB, Oracle, and SQL Server. With the Amazon Redshift federated query feature, you can query transactional and operational data in place without moving the data. The federated query feature currently supports Amazon RDS for PostgreSQL, Amazon Aurora PostgreSQL-Compatible Edition, Amazon RDS for MySQL, and Amazon Aurora MySQL-Compatible Edition.

Amazon Simple Storage Service (Amazon S3) is the recommended service for multi-format storage layers in the architecture. It offers industry-leading scalability, data availability, security, and performance. Organizations typically store data in Amazon S3 using open file formats. Open file formats enable analysis of the same Amazon S3 data using multiple processing and consumption layer components. Data in Amazon S3 can be easily queried in place using SQL with Amazon Redshift Spectrum. It helps you query and retrieve structured and semi-structured data from files in Amazon S3 without having to load the data. Multiple Amazon Redshift data warehouses can concurrently query the same datasets in Amazon S3 without the need to make copies of the data for each data warehouse.

Data outbound services

Amazon Redshift comes with the web-based analytics workbench Query Editor V2.0, which helps you run queries, explore data, create SQL notebooks, and collaborate on data with your teams in SQL through a common interface. AWS Transfer Family helps securely transfer files using SFTP, FTPS, FTP, and AS2 protocols. It supports thousands of concurrent users and is a fully managed, low-code service. Similar to inbound processes, you can utilize Amazon API Gateway and AWS Lambda for data pull using the Amazon Redshift Data API. And AWS Data Exchange helps publish your data to third parties for consumption through AWS Marketplace.

Consumption services

Amazon QuickSight is the recommended service for creating reports and dashboards. It enables you to create interactive dashboards, visualizations, and advanced analytics with ML insights. Amazon SageMaker is the ML platform for all your data science workload needs. It helps you build, train, and deploy models consuming the data from repositories in the data hub. You can use Amazon front-end web and mobile services and AWS IoT services to build web, mobile, and IoT endpoint applications to consume data out of the data hub.

Data governance services

The AWS Glue Data Catalog and AWS Lake Formation are the core data governance services AWS currently offers. These services help manage metadata centrally for all the data repositories and manage access controls. They also help with data classification and can automatically handle schema changes. You can use Amazon DataZone to discover and share data at scale across organizational boundaries with built-in governance and access controls. AWS is investing in this space to provide more a unified experience for AWS services. There are many partner products such as Collibra, Alation, Amorphic, Informatica, and more, which you can use as well for data governance functions with AWS services.

Security and monitoring services

AWS Identity and Access Management (AWS IAM) manages identities for AWS services and resources. You can define users, groups, roles, and policies for fine-grained access management of your workforce and workloads. AWS Key Management Service (AWS KMS) manages AWS keys or customer managed keys for your applications. Amazon CloudWatch and AWS CloudTrail help provide monitoring and auditing capabilities. You can collect metrics and events and analyze them for operational efficiency.

In this post, we’ve discussed the most common AWS services for the respective solution components. However, you aren’t limited to only these services. There are many other AWS services for specific use cases that may be more appropriate for your needs than what we discussed here. You can reach to AWS Analytics Solutions Architects for appropriate guidance.

Example architectures for gaming use cases

In this section, we discuss example architectures for two gaming use cases.

Game event analysis

In-game events (also called timed or live events) encourage player engagement through excitement and anticipation. Events entice players to interact with the game, increasing player satisfaction and revenue with in-game purchases. Events have become more and more important, especially as games shift from being static pieces of entertainment to be played as is to offering dynamic and changing content through the use of services that use information to make decisions about game play as the game is being played. This enables games to change as the players play and influence what works and what doesn’t, and gives any game a potentially infinite lifespan.

This capability of in-game events to offer fresh content and activities within a familiar framework is how you keep players engaged and playing for months to years. Players can enjoy new experiences and challenges within the familiar framework or world that they have grown to love.

The following example shows how such an architecture might appear, including changes to support various sections of the process like breaking the data into separate containers to accommodate scalability, charge-back, and ownership.

To fully understand how events are viewed by the players and to make decisions about future events requires information on how the latest event was actually performed. This means gathering a lot of data as the players play to build key performance indicators (KPIs) that measure the effectiveness and player satisfaction with each event. This requires analytics that specifically measure each event and capture, analyze, report on, and measure player experience for each event. These KPIs include the following:

  • Initial user flow interactions – What actions users are taking after they first receive or download an event update in a game. Are there any clear drop-off points or bottlenecks that are turning people off the event?
  • Monetization – When, what, and where users are spending money on in the event, whether it’s buying in-game currencies, answering ads, specials, and so on.
  • Game economy – How can users earn and spend virtual currencies or goods during an event, using in-game money, trades, or barter.
  • In-game activity – Player wins, losses, leveling up, competition wins, or player achievements within the event.
  • User to user interactions – Invitations, gifting, chats (private and group), challenges, and so on during an event.

These are just some of the KPIs and metrics that are key for predictive modeling of events as the game acquires new players while keeping existing users involved, engaged, and playing.

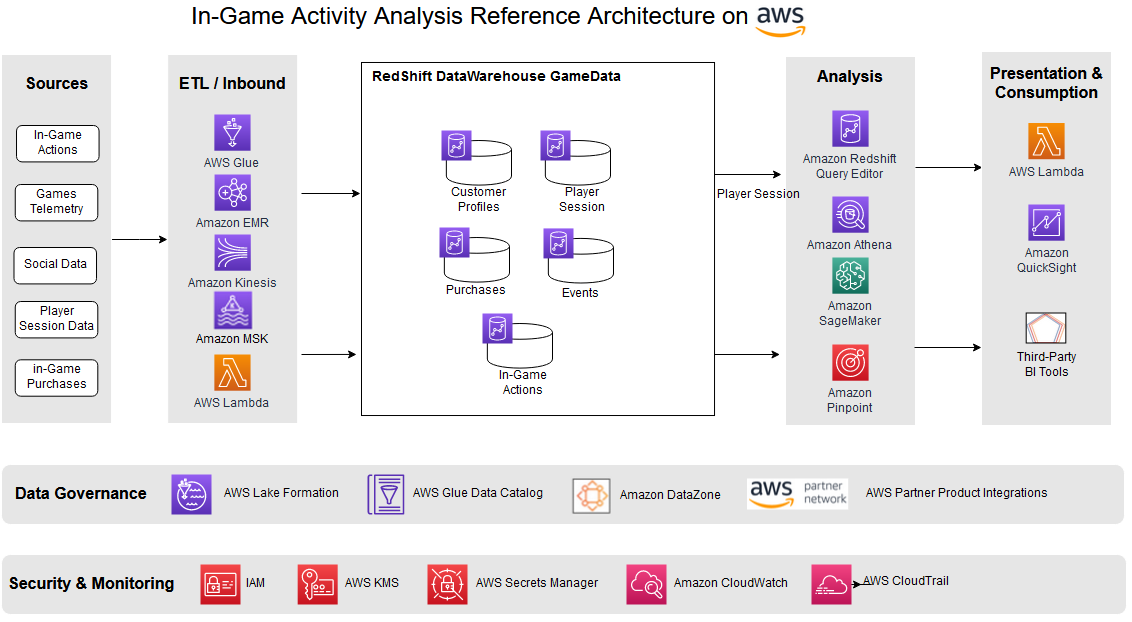
In-game activity analysis

In-game activity analysis essentially looks at any meaningful, purposeful activity the player might show, with the goal of trying to understand what actions are taken, their timing, and outcomes. This includes situational information about the players, including where they are playing (both geographical and cultural), how often, how long, what they undertake on each login, and other activities.

The following example shows how such an architecture might appear, including changes to support various sections of the process like breaking the data into separate warehouses. The multi-cluster warehouse approach helps scale the workload independently, provides flexibility to the implemented charge-back model, and supports decentralized data ownership.

The solution essentially logs information to help understand the behavior of your players, which can lead to insights that increase retention of existing players, and acquisition of new ones. This can provide the ability to do the following:

  • Provide in-game purchase recommendations
  • Measure player trends in the short term and over time
  • Plan events the players will engage in
  • Understand what parts of your game are most successful and which are less so

You can use this understanding to make decisions about future game updates, make in-game purchase recommendations, determine when and how your game economy may need to be balanced, and even allow players to change their character or play as the game progresses by injecting this information and accompanying decisions back into the game.

Conclusion

This reference architecture, while showing examples of only a few analysis types, provides a faster technology path for enabling game analytics applications. The decoupled, hub/spoke approach brings the agility and flexibility to implement different approaches to analytics and understanding the performance of game applications. The purpose-built AWS services described in this architecture provide comprehensive capabilities to easily collect, store, measure, analyze, and report game and event metrics. This helps you efficiently perform in-game analytics, event analysis, measure player satisfaction, and provide tailor-made recommendations to game players, efficiently organize events, and increase retention rates.

Thanks for reading the post. If you have any feedback or questions, please leave them in the comments.


About the authors

Satesh Sonti is a Sr. Analytics Specialist Solutions Architect based out of Atlanta, specialized in building enterprise data platforms, data warehousing, and analytics solutions. He has over 16 years of experience in building data assets and leading complex data platform programs for banking and insurance clients across the globe.

Tanya Rhodes is a Senior Solutions Architect based out of San Francisco, focused on games customers with emphasis on analytics, scaling, and performance enhancement of games and supporting systems. She has over 25 years of experience in enterprise and solutions architecture specializing in very large business organizations across multiple lines of business including games, banking, healthcare, higher education, and state governments.
Monday Night Itch #1: Mystery Trap Adventure

Post Syndicated from Eevee original https://eev.ee/blog/2022/01/31/monday-night-itch-1-mystery-trap-adventure/

Welcome to Monday Night Itch, a harebrained scheme to encourage folks to play more non-AAA games by adding a touch of social gamification. I thought I would be tweeting my adventures here, but I just had an experience so profound it can only be captured within a blog post.

The rules

Rules” is a strong word, but nevertheless:

  • Every Monday, find a game on itch.io, and pay at least $2 for it.

    You can buy a game with a price tag, or download a free game and leave a tip, but the point of this endeavor is to put money into more places in the ecosystem. (Note that it is possible, though uncommon, for a developer to disable payments altogether.)

  • Play it.

  • Leave a nice comment.

  • Tell at least one person what you played, and what you thought about it.

That’s it. Buy a game, play it, tell someone about it. You can stream it, tweet it, screenshot it, or just tell your boyfriend about it. You don’t have to like it

Your score is how many times you’ve done this, and your streak is how many weeks you’ve done it in a row.

Some other quick tips about itch

The itch app is cool. It’s a pretty thin wrapper around the website, but it adds automatic updating and big red “Launch” buttons and other stuff to make it feel a bit more like a Steam-ish thing. Do keep in mind that devs can upload whatever they want, and sometimes the itch app gets confused.

If you’re not a fan of running mystery software you downloaded from the Internet, you can just play web games and leave tips on those.

There are a lot of NSFW games on itch, but they’re hidden from the main browse pages by default. You can enable them site-wide in your user settings, or add /nsfw to the end of a browse page URL (for example, https://itch.io/gameshttps://itch.io/games/nsfw) to force a list of only NSFW games.
The main event

I decided I wanted to reward Linux releases, and also chip a few bucks towards games with a price tag that aren’t necessarily getting much exposure, so I went to the full list of recent paid Linux games. This is how I discovered Mystery Trap Adventure.
I found myself very much wanting to play this, but I also found myself wondering what sort of impact I should be trying for as the very first iteration of this project. Would I torpedo it if I played a game made by a less experienced dev? Are people looking to this expecting me to uncover unknown indie gems, like I’m wandering a beach with a metal detector?

I checked the dev’s itch profile and this is their ninth project. Every single previous work of their has only a single comment: from them, announcing that comments can be left below. That’s heartbreaking to me, and what made me absolutely sure I wanted to play this. I want to make their day.

And then, dear reader, I felt ashamed. Because who the fuck cares. The world already has enough people who believe that indie games are only valuable if they create the illusion of an eight-digit budget, and I am not here to enable them. Creative work does not need to be polished, mass-appeal, least common denominator stuff handed down from heaven by a billion-dollar international corporation in order to be interesting or worthwhile.

But more importantly, it’s my thing and I’m gonna do whatever the hell I want.

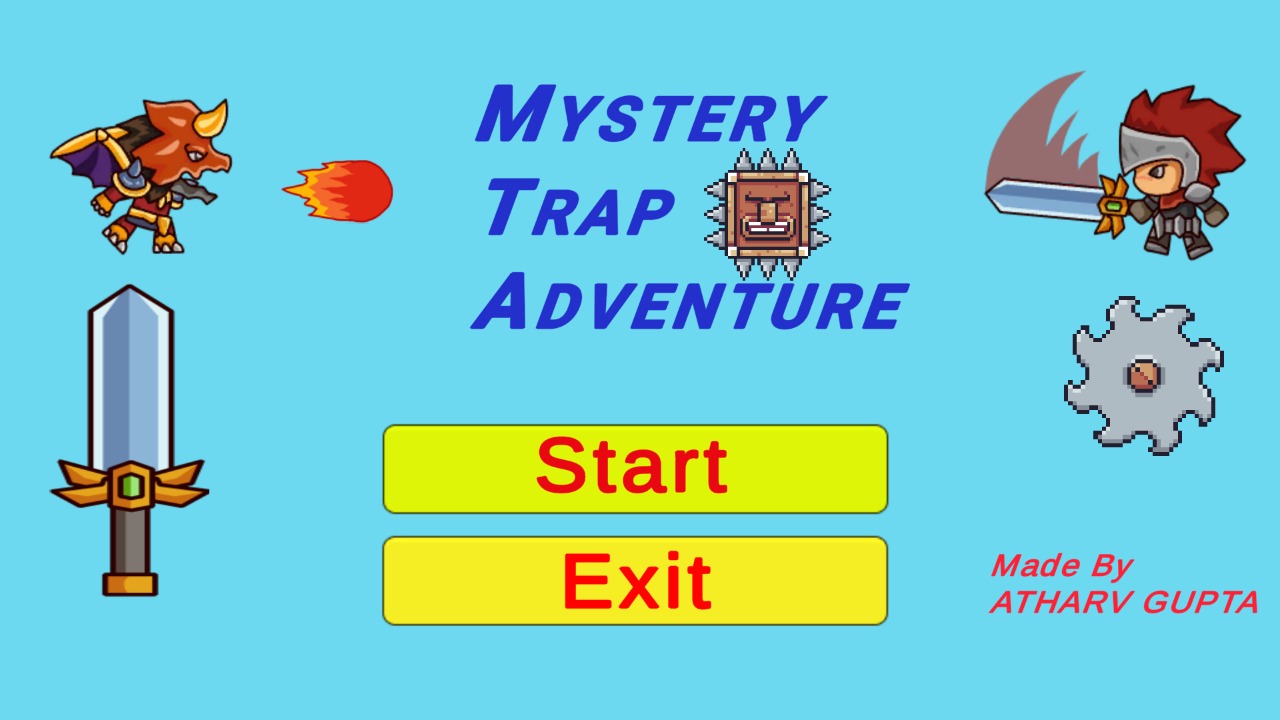
The title screen for Mystery Trap Adventure: a collage of mismatched artwork on a nearly cyan background

And so, Mystery Trap Adventure.

The first thing to note is that the game does not, in fact, have a Linux release. I did strongly suspect this, since a single download is flagged as all of Windows, Mac, and Linux, but the only way to be sure was to buy it. (They’re asking $4; I paid them $10.) Even Wine had trouble with it, for some reason, so I had to play it on our Windows media center.

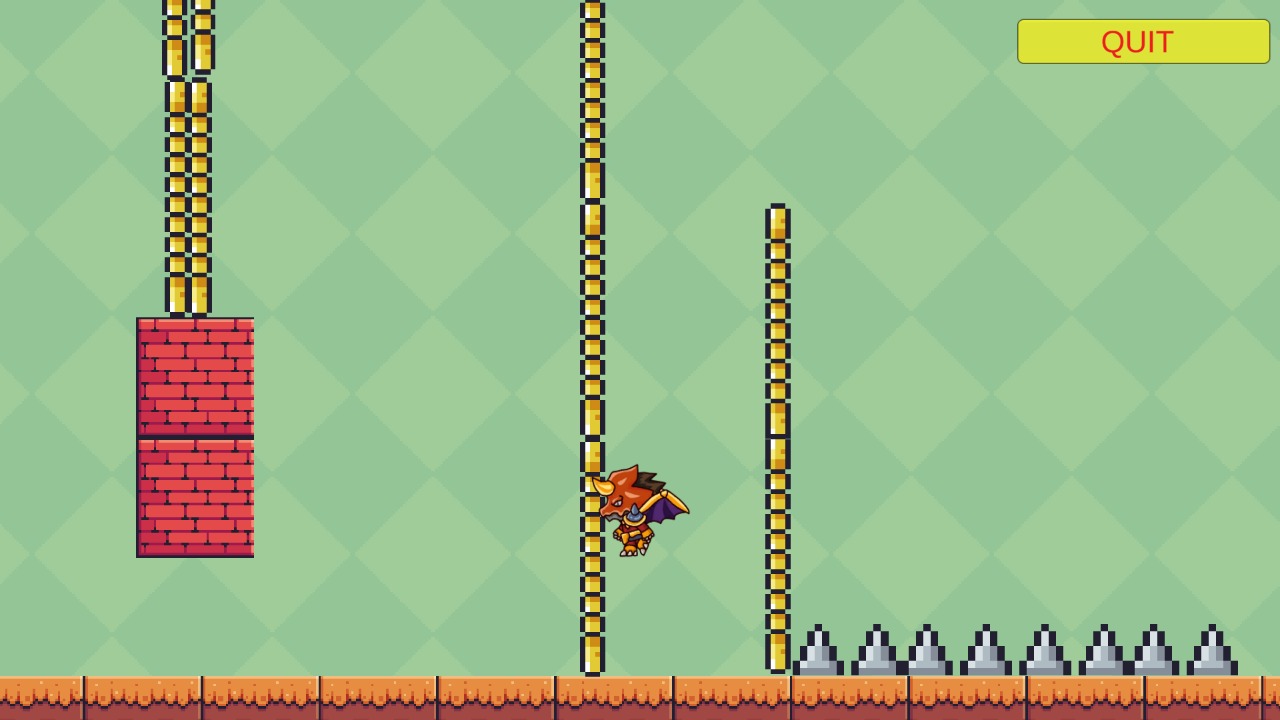
It’s a sidescrolling platformer where you play as a dragon; you can jump about one tile high (roughly your own height) and shoot fireballs (useful for destroying bricks and defeating the boss). The main obstacle is spikes, which kill you instantly.

Right at the beginning, there’s a block you have to jump on top of, and it was very obvious that I sort of “stuck” to the side of it if I touched it. I thought at first that this was the result of a common platforming gotcha: if you model the player as a dynamic body and implement movement (including air control) as a force on them, then they will stick to walls as long as the corresponding direction is held. This happens because forces on dynamic bodies are external, as though a giant ghost hand were pushing them — so if a player is trying to air control into a wall, the friction against the wall will hold them in place, just as if you were holding a book against a wall with your hand.

(Solving that problem is beyond the scope of this post, sorry.)

Okay, common pitfall, no big deal. I wander ahead a bit. I encounter a slice of watermelon, which allows me to teleport a short distance once. I screw this up the first time while messing with the controls — there’s a wall directly in front of it, so the teleport must be used to skip past that wall — and have to restart.

Now something interesting happens. I’m in a pit with walls on both sides. I can’t teleport again, and even if I could, there are spikes beyond the next wall, so that would kill me immediately.

A screenshot of the situation just described

It dawns on me that this microscopic game has walljumping.

I’m still fairly certain that the player character is a dynamic body, but now I wonder: is the wall stickiness actually due to the friction interaction, or is it a deliberate feature to enable walljumping?

Or, perhaps more likely, is it both? Did the developer trip over this pitfall, and decide to make a gameplay feature out of it? It almost seems unbelievable. I wouldn’t consider walljumping a basic platforming ability, and it’s not obvious how to solve the friction problem, but it seems that this relatively new developer may have solved both problems by simply smashing them together.

And if that’s the case, dearest reader: I fucking love it. That is the true spirit of game development, I think — you have a big complicated simulation you want to make, and you have a big complicated engine that you want to make do it, and you have to kinda mold both of them into fitting better with the other.

I don’t know. I could be completely wrong about this came to be. Or they could have copy/pasted from someone else who had this idea. Either way, it made me smile to see.

The walljumping controls are, ahem, not exactly intuitive, which is why it took me nonzero time to realize it was an ability at all. But honestly, I liked that too. Nowadays, everyone knows exactly how every platforming ability is “supposed” to work, because devs are all copying the same ideas from each other that have been refined over a thousand different iterations. This reminded me of playing games in the early and mid 90s, before everything had standardized as much, when part of the game itself was just working out the right muscle memory to make the right things happen. It’s surprising to find nostalgia in a game because it’s not like others I’ve played before, but there it was. Working out the right timing without any visual cues felt like a puzzle in itself, and getting out of the pit without landing in the spikes was remarkably satisfying. (If it helps: I used different hands for movement and jumping, and I landed on top of the right wall before trying to jump over the spikes.)

Beyond this, the tone changes somewhat to IWBTG-esque traps with no telegraphing. Walking directly to the right will cause spikes to appear from the ground, killing you instantly. Thankfully there aren’t too many of these, and the game is very short, so simply memorizing the handful of places they appear is easy enough.

I have less to say about the rest of the game; you get another quirky powerup you only use once, dodge another couple surprise traps, and face a single boss. The boss is a very large human warrior dude who walks straight at you and swings his sword, which kills you. There’s another fruit above you, but it seems out of reach. He is definitely too tall to jump over. The only solution I found is to simply spam fireballs at him before he can reach you, but I don’t know if this is intended. It seems like it can’t be, since his “health bar” takes the form of a grid of his face behind him, and from where you enter the area, you can’t actually see the whole grid? So surely I’m supposed to be able to get further to the right? But I don’t know.


I finished the game and came back to the following reply to my original thread about this whole concept:

most, i.e. all, small Indy games are terrible.

What a snotty, entitled, mean-spirited sentiment. As if the very existence of a game with lower production values than Resident Evil 8 were a personal offense. It seems to be fairly common, too, and I just do not understand it. Small indie games aren’t trying to squeeze you for more money, lure you in with gambling, exploit your friendships, make your entire life revolve around them. They’re just there.

This attitude is like showing up to everyone who mentions YouTube just to proclaim that everything on it sucks, because Paramount movies are better. That’s great, no one asked! Sometimes I just want to see a seven-second clip of a kitten filmed in a dark room by a $20 phone, because dammit, kittens are still fun to watch. No one makes a point of dunking on videos like that, so I don’t know why anyone is so harsh on amateur games either. Especially when making games is so much more difficult!

Mystery Trap Adventure is that video. Someone had an idea, worked out how to express it, and put it out into the world just because they wanted to. I don’t expect anyone else to buy it or play it; I just want you to know that I did, and it made me smile for a few minutes.

Including Hackers in NATO Wargames

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2021/01/including-hackers-in-nato-wargames.html

This essay makes the point that actual computer hackers would be a useful addition to NATO wargames:

The international information security community is filled with smart people who are not in a military structure, many of whom would be excited to pose as independent actors in any upcoming wargames. Including them would increase the reality of the game and the skills of the soldiers building and training on these networks. Hackers and cyberwar experts would demonstrate how industrial control systems such as power supply for refrigeration and temperature monitoring in vaccine production facilities are critical infrastructure; they’re easy targets and should be among NATO’s priorities at the moment.

Diversity of thought leads to better solutions. We in the information security community strongly support the involvement of acknowledged nonmilitary experts in the development and testing of future cyberwar scenarios. We are confident that independent experts, many of whom see sharing their skills as public service, would view participation in these cybergames as a challenge and an honor.