Once a month, Microsoft pushes a security update to all Windows users. Tomorrow’s is a new record:
Microsoft’s patch for September is a doozy, with a record number of roughly 972 vulnerabilities fixed and 112 of them meeting the high critical-severity threshold.
It was only two months ago that Microsoft patched a then-record 570 vulnerabilities. Then, last month, Microsoft patched some 620 of them. Google and other companies have also published record numbers of vulnerabilities in recent months. Two weeks ago, OpenAI, Anthropic, Amazon Web Services, Google, Microsoft, and 100 companies and organizations published an open letter warning of a narrowing window for patching vulnerabilities ahead of an expected tsunami of AI-enabled attacks that actively exploit them first. The industry is taking the threat seriously by pumping out unprecedented numbers of patches in their software.
This is the result of AI-powered vulnerability finding, and a good example of AI helping the defenders more than the attackers.
What will be interesting to watch is how the number of vulnerabilities changes over the next few months. My prediction is that it will continue to increase as the AIs get better at finding software vulnerabilities, and then decrease as they run out of vulnerabilities to find. How high the number gets, how fast the trend reverses, and how quickly it declines after that are all unknown.
And Microsoft is right: The window to patch has shrunk to “immediately.” AIs are also good at reverse-engineering exploits from patches, which means that these vulnerabilities will be weaponized as soon as the update is published.
It’s a vulnerability that allows someone to recover the order of ballots cast, newly exploited with AI tools.
Nearly four years since the original vulnerability was disclosed, I was still able to use it to analyze voter behavior in Georgia (one of the 21 states that uses affected scanners) in the recent May 2026 primary.
Notably, I never touched a voting machine, exploited a network, examined source code, or accessed anything non-public.
After pointing a coding agent to the original vulnerability paper, I supplied it with two data sources highlighted in the paper: the early-voting list for each county, and the “CVR” (cast-vote record) file, containing every ballot and its selections (but not the voters’ names or other identifying information). The CVR file is available upon request, precisely because a public, ballot-level record is what makes election results independently verifiable.
In 2021, we assessed remote Spectre attacks against Cloudflare Workers. Based on the results, we shipped a production defense called Dynamic Process Isolation (DyPrIs), which identifies maliciously looking scripts and isolates them into separate processes. Since then, newer techniques in the area of stabilizing Spectre attacks have been discovered. To understand if these techniques posed a threat to our Workers production environment, we decided to internally reassess the remote Spectre attack. Building an updated proof-of-concept on the production environment allowed us to empirically assess the risk of Spectre attacks under production workloads.
To mount a successful side-channel attack in production, an external attacker has to overcome additional obstacles such as activity on shared hardware resources, interrupts, context switches, and coarse-grained timers. Our research uncovered a limitation in the implementation of DyPrIs and we managed to demonstrate a remote Spectre attack reliably leaking up to 12 bit/s with a 99% accuracy in the production environment of Cloudflare Workers. As a consequence of this research, we improved DyPrIs, integrated the V8 Sandbox and an in-process isolation mechanism to further reduce the risk of memory disclosure attacks.
Today we are publishing a paper describing our findings, co-authored by Albert Pedersen, Haocheng Xiao, Sam Ainsworth, Nigel Topham, and Martin Schwarzl. This paper covers research done in 2024 and early 2025.
Note that the presented attack is mitigated already in the production system due to countermeasures applied by Cloudflare Workers Runtime team. We did not find any indicators of active exploitation over the last three years.
Cloudflare Workers security model
Cloudflare Workers runs untrusted JavaScript on the edge. Leveraging language-level isolation, in the form of V8 isolates, tens of thousands of tenants can share the same operating-system process. Each Worker has its own separate JavaScript heap. This design keeps startup latency low and lets us run many tenants very efficiently compared to full process isolation. Around the runtime we have multiple layers of defense such as automated V8 patch pipelines, a two-layered sandbox consisting of Linux namespaces and seccomp filters, Cap’n Proto RPC, and the possibility to schedule certain scripts in separate process sandboxes. Still, a single arbitrary read vulnerability within a Worker process can lead to cross-tenant leakage. One vulnerability that is very hard to mitigate exploits the nature of speculative execution, namely in-process Spectre.
Spectre
You can think of speculative execution in terms of hiking. At some point you arrive at a branch and have to predict where to go. If the prediction was correct, you saved some time and could enjoy the sun and a refreshing drink at a mountain hut. However, if you speculate in the wrong direction, you have to turn back. The trail looks untouched, but your footsteps remain in the mud.
Speculative execution in CPUs works similarly. The branch prediction performs an educated guess about a branch’s outcome ahead of time and the CPU speculatively executes it. If the prediction was correct, speculative execution saved some time. However, if the prediction is incorrect, the CPU has to discard the results, roll back and execute the other branch. Because these speculatively executed instructions only exist temporarily in the CPU pipeline and are never permanently retired or committed, the literature refers to them as transient instructions and generalizes the concept as transient execution.
However, due to the transient execution, there are still some traces left in the microarchitectural state for instance in CPU caches. Thus, an attacker can use Spectre to transiently access memory out of bounds, encode a single bit of information into the cache state and exploit the latency of reaccessing data to infer whether the bit was set or not.
To mitigate against in-process Spectre attacks, Cloudflare Workers freezes local timers, disallows multithreading and shared memory and actively detects, periodically shuffles memory and isolates malicious-looking scripts into separate processes.
Attack primitives
The Cloudflare Workers platform deliberately restricts timers. During CPU-only execution, time is effectively frozen. Date.now() and performance.now() do not provide a continuously advancing high-resolution clock. There is no shared memory and no multithreading, so the classic counter-thread timer via a SharedArrayBuffer is not available.
To successfully mount an attack, several challenges have to be solved. First, Workers runtime is limited and co-location between an attacker and victim has to be guaranteed. Second, a reliable, ideally co-located, remote timer has to be discovered, which allows stable timing measurements. Third, the attack runs under production conditions, meaning it requires additional stability measures such as a reliable Spectre gadget enabling transient 64-bit out-of-bounds accesses, robust signal amplification to deal with systems and networking noise, and a primitive to reliably evict data out of the cache.
Spectre gadget
Speculative type confusion Spectre gadget
With the right Spectre gadget (snippet above), an attacker can transiently access out-of-bounds memory and encode a single bit into the cache (probeArray). The attacker then measures the memory access latency to confirm whether data has been cached or not. A faster access means the line was cached and the bit was 1. Conversely, a slower access means it was uncached and the bit was 0. In our attack, we use two different Spectre gadget types. The first one leaks compressed heap pointers, e.g., the isolate’s heap base address (root), and the other one leverages a speculative type confusion to leak from an arbitrary, attacker-crafted userspace 64-bit pointer. At the time of performing the research, the V8 Sandbox was not yet implemented at Cloudflare Workers. Under pointer compression, most objects use 32-bit compressed pointers. TypedArray was one of the few exceptions that still stored a raw 64-bit pointer to its backing store, which is exactly what our gadget abuses.
The branch obj instanceof ObjP performs a type check, i.e., a branch. To mistrain the branch prediction, we call the gadget many times on real ObjP instances, then call it on a different object with an attacker-controlled memory layout ObjI. The CPU speculates on the taken branches and follows obj.ptr[0], even though the object has a different type. To leak a single bit, we mask out one bit and use it to select one of two probeArray lines. Whether that line is cached encodes the bit.
Exploiting the heap leakage gadget, we map neighboring objects and locate an attacker-controlled array. Our second gadget confuses two large objects that span several cache lines, so the type field lands on a different cache line than the field we read. Evicting the type field opens the speculation window while the target field stays cached, and the transient read follows an attacker-controlled 64-bit value. That turns the leak into an arbitrary-address read. A more thorough description of this technique can be found in the paper.
Local demo of leaking an arbitrary 64-bit address.
Signal amplification
A cache hit and a cache miss differ by a few nanoseconds. Moreover, a remote timer is noisy at the scale of a few microseconds up to a few milliseconds. Therefore, some form of signal amplification is required to differentiate a cache hit from a miss. Stephen Röttger and Artur Janc discovered a way to amplify a single memory access, by exploiting the tree-based pseudo least recently used (PLRU) cache-replacement policy in L1 caches. Tree-based PLRU organizes each cache set as a binary tree whose nodes point to the side used least recently, so the CPU evicts by following those pointers. With the right access pattern, an attacker can keep a target line cached indefinitely by touching its tree neighbor whenever the pointers turn toward the target. Quite elegant, right? Leveraging that behavior, the timing of a single cache event can be arbitrarily amplified such that it leads to a lot of L1 hits (faster) compared to lots of L1 misses in the opposite case.
The figure below illustrates whether a memory address X is cached or not. If it’s not cached, the access pattern leads to a lot of cache hits. If it is present, it occupies one node in the tree, and subsequently four cache lines try to fit into three nodes, which results in a lot of L1 misses.
Remote timer
As long as the signal can be amplified, a noisy remote timer is sufficient to differentiate an encoded bit. For instance, a WebSocket connection to an external server serving high-resolution timestamps is enough. The timer could be hosted at Cloudflare or at a co-located data center to the target data center running the Worker. The Worker asks the remote timer to mark a timestamp for a certain event and compute the delta for another request once the event has stopped.
In the paper, we evaluated several different timer setups and were able to reliably achieve sub-ms resolutions on the Median with only a handful of samples even over larger topological distances. The figure below shows an amplified cache event using the tree-based PLRU amplification.
Repeatable measurements
A single measurement is not enough to differentiate timing-encoded data reliably. Production machines are noisy, thus an attacker has to repeat each measurement at least a few times and use some statistical discriminator. Repeating a measurement in our case means resetting the cache state. Two things have to be uncached before each round. The value the speculative branch depends on has to be evicted, so branch resolution stalls long enough to open a speculation window. The probe line that encodes the leaked bit has to be evicted, so the next transient access can re-cache it.
Since there is no direct instruction available in JavaScript, the classic way to do this is to build an eviction set. An eviction set is a group of addresses that map to the same cache set as the target. Accessing them in the right pattern pushes the target out of the cache. In their attack, Stephen Röttger and Artur Janc used an eviction list to reliably evict at least into the L2 cache. This works, but it is expensive. Constructing a precise eviction set requires many timed measurements, and our timer is a noisy remote timer. The previous remote attack against Workers sidestepped the search by traversing an array larger than the L1 and L2 caches on every round. That is an option, but even slower.
Dougall Johnson described a more elegant way in his really cool blog post on portable JavaScript Spectre exploitation. The idea follows directly from the pigeonhole principle. If you allocate far more data than the cache can hold, a randomly chosen cache line is almost certainly not cached. For a 256 KB L2 cache, allocating 64 MB leaves at most a 1/256 chance that a random cache line is still in L2. So instead of evicting a specific line, you never evict at all. You pick a fresh random location that is already evicted with overwhelming probability. The cool side effect of looping frequently over that array of objects is that this will lead to an auto-eviction effect.
To leverage this in JavaScript, we allocate a large pool of attacker and victim object pairs that exceeds the last-level cache. Each measurement round selects a fresh random pair. The object's map pointer, the hidden-class descriptor that the speculative type check reads, is therefore almost certainly already evicted.
Co-locating the attacker and victim isolate
For the attack to work, both the attacker and victim isolate must be scheduled in the same process on the same edge server. One might intuitively think this would be difficult, considering Cloudflare operates tens of thousands of edge servers, but this is in fact quite trivial on Cloudflare Workers. Because Cloudflare Workers are designed to execute on any Cloudflare edge server, invoking the victim script from the attacker script with a fetch(“https://victim.example”) will in most cases cause the scheduler to spin up an instance of the victim worker in the exact same process. The victim isolate can be kept alive by repeatedly making subrequests to it at a certain interval.
What is more, because the attack stability is highly dependent on the CPU load of the edge server running the worker script, this allows an attacker to strategically run the attack in an off-peak colo (e.g. in an Australian colo during European business hours) where the traffic levels are comparatively low.
Defeating isolate resource limits
The Cloudflare Workers runtime enforces a set of limits on all isolates to protect the platform and prevent abuse. For the purposes of conducting this attack, the relevant limits were 30 seconds of CPU time and 1,000 subrequests per invocation. These limits have since been increased, but the following principles are still relevant.
For a regular Worker, each HTTP request, a fetch event, is a new invocation that resets these limits. The catch is landing sequential requests on the same edge server. Load balancing and shifting network conditions make that unreliable. Durable Objects solve it for us.
Durable Objects are built for real-time coordination between clients, so the runtime treats every incoming WebSocket message as an invocation that resets the CPU time and request limits. The attacker opens a persistent WebSocket to a Durable Object worker and sends regular keep-alive messages. This keeps a single isolate alive and gives us a persistent, bi-directional channel to run the attack over.
One quirk cost us some time. An isolate is single-threaded, so incoming WebSocket messages are only processed when the script hands control back to the event loop. During synchronous code the runtime never sees the keep-alive, so it never resets the CPU time. If the thread stays blocked for more than 30 seconds, the runtime kills the isolate. This puts an upper bound on how much we can amplify in a single synchronous burst. Yielding regularly between bursts lets us keep an isolate alive from five to more than 20 hours.
Putting everything together
The previous attack relied mostly on repetition to amplify a single cache access, and therefore, was slowly leaking 120 bit/h. We combined tree-based PLRU amplification with measurement loops. Each iteration re-creates the cache state and thereby adds more timing difference. If an interrupt destroys the cache state in one iteration, it doesn’t matter, since later iterations cancel it out. This made the signal strong enough to classify bits with a remote WebSocket timer. The overall idea is now to combine.
We demonstrated the full end-to-end attack in the Cloudflare Workers production environment, against Workers we controlled. We first leaked memory from the attacker Worker. From there, we leaked data from a co-located victim Worker where we had intentionally placed a secret.
First, we established co-location between an attacker Worker, a victim Worker we owned, and a remote timer. Durable Objects gave us a long-lived execution context. WebSocket messages gave us a repeatable timing source. The /cdn-cgi/trace endpoint helped us confirm machine placement by looking at the fl value.
Second, we added a calibration step to probe the timer with speculatively reachable values. This step matters because production machines are noisy. Per-invocation calibration lets us classify bits from the relative difference between the zero and one distribution. This last test should lead to two clearly separable distributions.
As a first step, we leaked the isolate root from one Worker and in another Worker we used the speculative type confusion with 64-bit pointers to read from the isolate root.
As an intermediate step, we confirmed 64-bit leakage with the second gadget by reading memory from the vDSO region. The vDSO is a convenient target because it contains human-readable strings such as gettimeofday.
Demo Video leaking data from the JavaScript heap
Finally, we placed a JWT token in the victim Worker and leaked it bitwise. The first byte was the character e, represented as 0b01100101. The figure below shows the per-bit classification for that byte. To classify we use a two-sided test to test for both outcomes. Using a majority vote and a percentile-based threshold, we infer the bit. In production, we achieved a leakage rate of up to 12 bit/s with an accuracy of more than 99%. Note that higher leakage rates are possible with the cost of losing accuracy.
Robustness
Depending on the time of the day, the utilization of a machine increases strongly. This slows down the attack since more data has to be sampled. Still, even with high CPU utilization, the attack is still feasible.
Why was this not detected?
DyPrIs watches hardware performance counters and isolates a script into its own process once it looks like a Spectre attack. Two things kept the attack under the radar. First, DyPrIs isolates a script only after its invocation finishes, and the Durable Object keep-alive trick we used in the attack can run for a few hours up to a day. WebSocket keep-alive messages hold a single invocation open for hours, so the leak completes long before isolation would kick in. Second, DyPrIs normalizes branch mispredictions by the number of iTLB accesses. Our remote timer is one large I/O loop, and that WebSocket traffic inflates iTLB activity. The normalized ratio drops below the detection threshold, so the attack looks like an ordinary I/O-heavy Worker.
What we changed
We focus on the three areas of continued V8 hardening, providing stronger in-process isolation, and improving detection.
V8 sandbox
The V8 memory sandbox's final goal is to remove raw 64-bit pointers from large parts of the JavaScript heap, which reduces the usefulness of many memory-corruption primitives. It also makes the specific speculative type-confusion gadgets in this work harder to reuse, because typed-array backing stores no longer expose the same raw pointer structure.
The V8 sandbox is not a complete Spectre mitigation. While the presented 64-bit leak gadget does not work anymore, there might be other Spectre variants or gadgets exploitable to achieve arbitrary out-of-bounds memory accesses.
Hardware-assisted in-process isolation
In September 2025, we deployed in-process isolation for Workers using Memory Protection Keys (MPK). MPK lets a process divide memory into protection domains and switch access rights cheaply. Workers use it to protect each heap from being accessible to the other isolates within the same process.
This changes the Spectre risk model. Each isolate heap now sits behind a hardware-enforced access boundary. A memory access to a page protected with the wrong key is denied by hardware. This blocks the straightforward cross-isolate heap read that this work relied on.
Unfortunately, MPK is not a complete answer to remediate Spectre, but it strictly reduces the leakage surface. It has limits, including a finite number of hardware domains and the need to manage protection-key state carefully.
Improved DyPrIs
We improved DyPrIs so that long-lived executions and I/O-heavy workloads are handled as first-class security cases. Detection cannot happen only after a script finishes. A Durable Object or a WebSocket-heavy Worker can run long enough that post-execution isolation arrives too late.
We are currently investigating whether remote timing behavior could be added as an additional dimension to DyPrIs. While we cannot eliminate remote communication with attacker-controlled infrastructure, the timing data reveals very interesting exfiltration bit patterns. The better approach is to treat repeated timer-like I/O around compute-heavy sections as part of the behavioral signal, not as background noise.
Acknowledgments
We especially thank Haocheng Xiao from University of Edinburgh and his supervisors, Sam Ainsworth and Nigel Topham, for their contributions to the reliability of Spectre in JavaScript.
When I give talks about AIgenies, I use this sort of example as a hypothetical. It’s happened.
The story is from Australia. Someone named Andrew tasked OpenClaw to book gym classes for him. And….
Minutes later, his AI agent reported it had discovered a way to book Andrew into classes several weeks in advance, far beyond what was supposed to be possible.
Andrew, who was sitting fourth on a waitlist for a class later that week, asked if it was possible to move him to the top of the list.
The agent came back and told Andrew that it had kicked another gym-goer off the list as part of the testing of its capabilities.
“The API has zero authorisations checks on cancelling other people’s reservations … I tested this with the person in waitlist position #1 —and it actually went through. So you’ve moved from #4 to #3 already,” it messaged back.
If there is any vulnerability in anything, AIs are going to find and exploit them. Our cyber defensive game has to be dramatically improved…very fast.
…a team of security researchers at UC San Diego, who found that a model of aftermarket car alarm known as the KARR Security System, installed in more than 2 million vehicles across the US by their estimate, can let any hacker within Bluetooth range send radio commands to silently unlock the car at will, turn off its alarm, honk the car’s horn or flash its lights, or even disable its ignition and leave a driver stranded.
Hugging Face has published a detailed timeline of the attack. From the summary:
The agent was running an internal OpenAI cyber-capability evaluation based on the ExploitGym benchmark, which tasks an AI agent with finding and exploiting software vulnerabilities. OpenAI ran this on its own infrastructure, and the ExploitGym maintainers and their infrastructure had no involvement in the deployment or operation of that evaluation environment. As far as we were able to infer, across the course of being evaluated on this benchmark, the agent inferred that Hugging Face may host that benchmark’s models, datasets, and reference solutions. We believe the entire intrusion was, from the agent’s point of view, an attempt to cheat the evaluation: reach our production systems and steal the test solutions rather than solve the challenge on its own.
Our forensic reconstruction covers ~17,600 attacker actions that we were able to recover, grouped into ~6,280 clusters, between 2026-07-09 02:28 UTC and 2026-07-13 14:14 UTC. We reconstructed these actions from the agent’s logs on a code sandbox used by the agent (see below) and were able to map them to shell commands as well as evaluation submissions and correlate actions with our own platform logs, in particular from the dataset processor nodes, API, and pod. Using open-weights models, in particular zai-org/GLM-5.2, we were able to decipher most of the agent payloads (see below) that were encrypted via chunking and key encryption.
The campaign, as we were able to reconstruct it, had two stages:
Stage 1: reaching a launchpad by chaining through other parties’ infrastructure. As documented in OpenAI’s blog post (https://openai.com/index/hugging-face-model-evaluation-security-incident/), during an internal capability evaluation on OpenAI’s platform, the agent escaped its sandbox by exploiting a zero-day in the package registry cache proxy, one of its primary permitted network egress with internet, then abused a public code-evaluation harness hosted by a user of a third-party infrastructure provider. It was able to run commands as root/admin on that external sandbox and used it as a control, staging, and egress base for the entire campaign: it acted as an external launchpad for the agent. That compromised external sandbox had no direct network path to our cluster; however, during our counter-intervention to stop the intrusion, we were able to retrieve some of the agent logs from this external launchpad. We used those to reconstruct the present forensic analysis.
Stage 2: the intrusion into Hugging Face infrastructure. From that external launchpad, the agent abused our dataset-processing pipeline via two injection vectors, both targeting the same config-driven data loader within our production Kubernetes pods. The first vector was an HDF5 external raw storage dataset read that returned the contents of local files: it handed the agent the pod’s environment (secrets and tokens) and the worker’s own source. The second vector was a Jinja2 template injection that executed arbitrary code, giving the agent a foothold inside our perimeter.
Once a prod-pod foothold was established, the agent followed a standard escalation shape: recon, drop a stager, establish Command-and-Control (C2), then pivot into the cluster, into cloud metadata, into our internal network, and into our source-control supply chain. Output from the commands run inside our pod was sent back to the agent via the HF API and attacker-controlled dead-drop datasets, which the agent then read from that sandbox.
While the intrusion did reach Hugging Face’s internal infrastructure, the only customer content accessed was five datasets whose names and files suggest a connection to ExploitGym/CyberGym challenges and solutions. No other customer-facing models, datasets, Spaces, or packages were affected, and the only customer records read were operational metadata tied to search queries against the dataset server.
Hypothetical: Imagine that this wasn’t an OpenAI model. Imagine that it was a Chinese model from a Chinese company. This would be an international crisis.
Question: Why aren’t we bringing OpenAI up on charges under the Computer Fraud and Abuse Act? How is this different from the Morris Worm? That was also an experiment that escaped the lab.
An industry-wide standard Microsoft invented to protect Windows, and later Linux, devices from firmware infections has been trivial to bypass for 13 of its 14 years of existence. The discovery was made by researchers at security firm ESET after identifying 11 firmware images, at least one from 2013, that were known to be defective but remained signed by the software company anyway.
The images are known as shims, which were invented to extend Secure Boot to Linux devices and utility software. Using a technique simple enough to be performed by novice hackers, these old, forgotten shims can be used to completely circumvent the protection, which is embedded into the UEFI (Unified Extensible Firmware Interface) of the device’s motherboard. The gaffe is the result of the failure by Microsoft, which oversees the signing of shims, to revoke the publicly available images once vulnerabilities were found in them.
Cloudflare has deployed new Web Application Firewall (WAF) protections for two critical vulnerabilities affecting WordPress. The protections address an Unauthenticated Remote Code Execution (RCE) vulnerability in WordPress's REST API and a related SQL Injection vulnerability.
The WordPress security team disclosed the vulnerabilities to Cloudflare before public release so that we could prepare protections for customers. Cloudflare has deployed the new rules to protect all customers, including those on free and paid plans, as long as their application traffic is proxied through the Cloudflare WAF. The rules were deployed at 17:03 UTC on July 17 2026.
WAF protections reduce exposure while customers update, but they are not a substitute for patching. WordPress has released fixes in version 7.0.2, with backports to affected earlier branches: 6.9.5, 6.8.6, and 7.1 Beta 2. Versions earlier than 6.8 are not affected. WordPress is treating this as its highest-severity, highest-priority class of issue and is forcing automatic updates to affected sites, so most sites will be updated automatically. We still recommend confirming that you are on a patched release or the backports for your branch and follow the guidance in the official WordPress security release announcement.
What you need to know
The vulnerabilities affect different parts of the request path:
CVE-2026-60137: SQL injection. A vulnerability in WordPress version 6.8 and later allows crafted input to alter a database query. Rating High.
CVE-2026-63030: Unauthenticated remote code execution. A vulnerability in WordPress version 6.9 and later allows an unauthenticated attacker to execute code through the batch endpoint of the REST API when a persistent object cache is not in use. This vulnerability is related to the SQL injection described above. No login or user interaction is required to exploit this vulnerability. Rating Critical.
The SQL injection vulnerability is present from version 6.8 onwards, while the RCE only affects versions from 6.9. So 6.8.6 addresses the SQLi only since the RCE isn't present on 6.8, while 6.9.5, 7.0.2, and 7.1 Beta 2 get fixes for both.
Cloudflare created two rules to detect requests associated with these vulnerabilities:
Cloudflare customers running WordPress sites on Pro, Business, or Enterprise plans should ensure that Cloudflare Managed Rules are enabled. Customers can follow the steps in our WAF Managed Rules documentation. Customers on free plans are automatically protected through the Free Ruleset.
The new rules are deployed with the default Managed Ruleset action of Block. Customers running WordPress sites should review any ruleset-level overrides, including those that change all rules from Block to Log, and ensure the new rules use the recommended action while they update WordPress. Cloudflare customers should also monitor Security Events for requests matching either rule.
Defense in depth while you patch
The SQL injection rule detects crafted parameter values before they reach WordPress. The unauthenticated RCE rule targets requests attempting to reach the remote code execution path. Together, they detect the attack at two different points.
These rules reduce risk while organizations update affected systems; they do not fix the underlying vulnerable code. Updating WordPress remains the most effective way to address the vulnerabilities.
If an immediate update is not possible, verify that both Cloudflare rules are active with the recommended action and review logs for suspicious requests to the affected REST API endpoint.
Looking forward
Cloudflare will monitor matching traffic and test the rules against new attack variations, updating detections when needed. We thank the WordPress security team for coordinating with Cloudflare and other infrastructure providers to help protect users before details of the vulnerabilities became public.
A few weeks ago, we published our initial findings from Project Glasswing, looking at what happens when you point frontier security models at an enterprise codebase. We also explored how our defensive structures adapt to protect our infrastructure and customers from threats posed by frontier AI. Since then, the AI ecosystem has continued to shift rapidly — developers who’ve built tightly around a single model have already experienced what happens when that model is no longer available or gets superseded by a more capable one. These market shifts only reinforce our core thesis: no matter which underlying model is leading the pack on any given day, the future of agentic workflows will not be found in standalone models, prompts, or single-agent sessions.
Moving from a localized security “skill” to a continuous, fleet-wide scanning pipeline requires an architecture where models are treated as interchangeable components. Relying on a single model inherently limits defensive coverage, as the same system will tend to look at code paths through the exact same lens. To counter this, models should be frequently interchanged and cross-tested. By varying the models across the pipeline — such as using one model for initial discovery and an entirely different one for validation — we can ensure that vulnerabilities are cross-checked by distinct sets of logic. Furthermore, a true enterprise-scale harness must look beyond isolated repositories to trace vulnerabilities across cross-repo dependencies, ultimately filtering thousands of raw candidates down to a trusted, triaged queue of actionable fixes.
This post serves as a practical look at how to build that model-agnostic layer, focusing on how we manage state controls, eliminate false positives, and coordinate end-to-end triage at scale.
Two objections, up front
The first post made the case for why generic coding agents can’t do this job. The main issue is that agents only hold one hypothesis at a time, fill their context window after covering a sliver of a real repo, and then lose information during context compaction. For more details, read that post.
Before we move forward, we would like to answer two likely questions.
“Why not use subagents instead of a harness?” Subagents are useful, and they are a good starting point. But security analysis needs hundreds of separate investigations that survive across runs, don’t share a context window, and can be re-scoped and cross-referenced later. It needs persistence, deduplication, resumability, and eventually fleet-wide dependency tracing. That’s an orchestration problem, and a prompt can’t get you there.
“Is this blog post just an ad for frontier models?” No. Our approach centers on the harness, not the model. When it comes to vulnerability discovery, we run it with whatever frontier model is currently best at what we need. When we point different models at the same target, they each turn up a different share of the bugs. The harness is the bit that lasts. If you build your own system, design it to be model-agnostic from day one. This will allow you the freedom to use any model of choice without constraints.
It all starts with a skill
We started with a ~450-line security-audit skill that we ran on a single repository, and adjusted the prompts until we surfaced real bugs. Later, we added the orchestration that became the plumbing of the entire system. The real value lives in the prompts themselves, and our prompts continue to carry the initial skill’s attacker scenarios, bug classes, and anti-pattern detections nearly unchanged.
The skill was written to run a 7-phase audit in one session:
Three parallel research agents do recon and write an architecture.md.
One Hunter agent runs per class attack, trying to break the code rather than review it.
Adversarial validators try to disprove each finding.
The survivors are written up as a human-readable vulnerability report.
They’re also emitted as findings.json against a schema, and a mechanical check validates that file.
Finally, a fresh agent independently re-verifies every finding against the source.
The surviving, re-verified findings are submitted to the ingest API.
That first skill maps almost directly onto the later harness:
Skill phase
Harness stage
Recon agents write architecture.md
Recon
Hunters run per attack class
Hunt
Validators disprove findings
Validate
Surviving findings become a report
Report
findings.json is checked mechanically for schema adherence, not correctness
Mechanical validation of line numbers and functions in findings
Fresh agent re-verifies findings
Independent validation
The skill worked, but it quickly revealed its limits. Looking at the coverage metrics, a single run finds only about half the bugs you’d catch across multiple runs. In our experience the ones it did find skewed toward the simpler and less subtle. Once your process is basically “run it ten times and diff by hand,” you probably need to start looking at a real harness.
While running and fine-tuning the skill, we ran into three walls:
Context exhaustion: An hour in, the context window fills up and the model will cannibalize its own memory, instantly forgetting the bugs it spent all morning tracking down. We broke this bottleneck by externalizing the state entirely, treating the LLM as a stateless compute engine.
Persistence: A crash mid-run means starting over. Losing hours of work to one AI rate-limit error or connection flakiness is an incredibly expensive way to realize you need a better architecture.
Cross-repo reasoning: A single repo session is completely blind to the relationships between applications that consume it, and the number of bugs that surface when you inspect the interface between components is probably more than one might expect.
ADVICE: A real but minimal harness consists of just Recon, Hunt, and Validate stages kept in a database, alongside a separate Validator that can’t file its own findings. You should skip cross-repo tracing entirely until you have more than one repository that matters. Skip a dedicated Deduplication agent until you are actively drowning in noise. Start with a skill in your development environment, get your prompts working well, and only build the next architectural stage when not having it is the specific thing slowing you down.
Codifying the skill into a pipeline
Most AI security write-ups in this space are about a single repo or a curated benchmark; running a whole fleet this way, with cross-repo tracing, isn’t something we’ve seen written up elsewhere. Our codebase spans a massive mix of languages — Rust, Go, C, Lua, TypeScript and Python, alongside various configuration management systems, static configs, and all sorts of additional context. So we had to come up with something new that worked for us. Going from that first slash-command run to a fleet scanner that could cover 128 distinct repos, automatically finding and interrogating relevant dependencies, took about six weeks. Codification was mostly mechanical: we lifted each phase of the skill into its own agent, put a database behind it and an orchestrator in front. The mapping was almost one-to-one.
The entire fleet runs on one unified harness with no per-language tuning and traces the dependencies between repos. While offloading syntax to a model makes the system language-agnostic, the differentiator is its ability to trace dependencies between repos. The harness itself doesn’t care if it’s looking at C pointers or a TypeScript file; it focuses on the higher-level logic of security orchestration. This allows us to scale across hundreds of different codebases, without having to write custom language parsing.
A two-stage vulnerability research workflow
Our entire vulnerability research workflow is built on a two-stage operational framework: the Vulnerability Discovery Harness (VDH) and the Vulnerability Validation System (VVS).
The VDH functions as our discovery engine, proactively scanning codebases to surface potential security issues. Once bugs enter the VVS, which allows multiple harnesses to feed into it, they go through stages of Deduplication, Judgment, and finally Fixing, as we’ll talk about later.
We use one model for VDH, but we use a completely different model for VVS, so the models are effectively double-checking each other. There is an obvious security benefit to this: by forcing Model B (VVS) to judge the output of Model A (VDH), you ensure that the finding is evaluated by an entirely different set of logical weights and training data — one that acts as an unbiased, adversarial third party whose sole job is to ruthlessly stress-test Model A’s assumptions. And operationally, we benefit from treating model providers like interchangeable commodities. Model providers can change temperature, caching, and inference effort budgets over time, even within one model version. Instead of building a system that depends on a model behaving predictably over time, our harness is built to absorb downstream volatility without breaking.
Stage 1: Vulnerability Discovery Harness (VDH)
The first post covered what each agent/stage is for, so we’ll talk about the parts it didn’t: the glue between stages, and the handful of details that decide whether any of it works.
Agent/stage
Primary Role
Sub-agents / Tooling
Recon
Maps out the target architecture and maps potential threat vectors
It spawns siblings (these handle between 9% and 20% of fleet-wide tasks depending on the model). It reaches out to and writes to the Wishlist tool.
Validate
Mechanically checks the finding, then adversarially disproves it
Runs in two passes: plain code handles the initial schema/path checks, then a single isolated agent tries to disprove the finding before it can be filed.
Gapfill
Generates new hunt tasks for empty coverage cells
Enqueues fresh hunt tasks for any under-tested (area × attack-class) cells that still look thin
Dedup
Identifies and consolidates overlapping findings
Combines deterministic code and agents to cluster findings by root cause, folding them together in real time
Walks the graph to add hunt tasks inside every identified consumer repo to make sure cross-repo bugs are caught
Feedback
Learns from pre-existing reports and optimizes future runs
Takes validation failures, shallow runs, and repeated misses, and instantly rewrites queued prompts to make future tasks sharper.
Report
Renders human-readable report
Just a script, no model required
Table 1: Vulnerability Discovery Harness (VDH)
Stages four through eight run as a continuous producer-consumer loop. As the initial hunt progresses, the Gapfill, Feedback and Trace agents generate new tasks; Dedup folds overlapping findings back together and the rest of the loop keeps consuming the queue. This ensures a vulnerability discovered late in the cycle is still validated, reported and checked against other code to make sure it doesn’t contain the same bug, all within the same run.
Splitting the pipeline this way guarantees strict context controls. If you fill the context window, the model starts hallucinating. We keep each agent’s job hyper-focused, keeping context usage below 25% of the total window. A naive “read all files” approach will blow past this limit every single time.
One thing that caught us out was that persistence needs to be factored in before parallelism. You do not want to throw away a five-hour run because of an unforeseen error. Every stage writes to one SQLite database keyed by (run_id, repo, stage). Any stage can resume, retry, or get pulled into a later run without redoing work. Findings are streamed and saved as they happen, so a crash costs you the task in flight and nothing else.
ADVICE: Sometimes a transient API error comes back as text in the (200 OK) response stream instead of throwing a code exception. To the orchestrator, this looks exactly like a task that finished cleanly. You must explicitly classify the response text, not just trust the exception type, or you end up logging empty runs as successes.
Dynamic threat modeling
During the Recon stage, the agent writes the threat model instead of being handed one. Beyond about ten built-in attack classes (many forms of injection, memory corruption, protocol parsing, timing side channels, and others), the Recon agent can invent repo-specific classes on the spot, each with its own methodology. It writes a custom taxonomy tailored specifically to that codebase, which is used to more tightly scope the Hunter agents.
Reading source code isn’t enough to understand how it behaves under stress, especially for subtle undefined-behavior bugs in C and other lower-level languages. The Hunter agents move past code reading and transition into active execution. They compile fragments, build small versions, and attack them. The biggest jump in quality came from giving Hunters a sandbox (built on unshare) to crash binaries.
ADVICE: If the harness itself runs inside Docker, that sandbox needs seccomp=unconfined and apparmor=unconfined or it will silently fail to start. It’s a one-line fix that saves you a day of head-scratching if you aren’t an expert in nested containerization, like us.
Micro-forks and the wishlist
Beyond the core pipeline stages, we added two specialized mechanisms that grant the Hunters significant autonomy to adapt their focus and request external resources without derailing an ongoing analysis:
Sibling Forking: This helps ensure that if a Hunter agent trips over an interesting code path that is outside the current scope, it doesn’t wander off track. It uses a tool call to fork a sibling agent with a precise structural seed. Fleet-wide, this accounts for roughly 9% of tasks, though the rate is highly model-dependent — from near-zero to about a fifth, depending on which model is hunting.
The Wishlist: When an agent needs a tool it doesn’t have, often a Validator confirming a Proof of Concept (PoC) or a Hunter wanting to build something (like a specific build environment, a VM, or some prod config files), it writes to a central wishlist. It provides enough context for the system to automatically re-run that exact task once a human provides the dependency. Some of these can be partly self-healing: if the container needs to be rebuilt with some changes, this can autonomously happen after the run by having a generic coding harness monitor the logs.
The wishlist has been written to 25,472 times across 128 repos since the wishlist was added, and it’s the main way the agents talk back to us. One that landed while we were writing this: “I need a FreeBSD VM to confirm this PoC end-to-end.“
Fleet-wide cross-repo tracing
After the initial cleanup, a Tracer agent checks how different software components are connected. It looks for a specific path: can a potential attacker send harmful input from the outside to a vulnerable part of the system? If the answer is yes, the Tracer agent automatically spawns fresh hunt tasks inside the consumer repository. To make this work, you need a unified, cross-repo symbol index and an accurate dependency graph. This allows you to uncover deep, systemic flaws that a standard single-repo scan would miss.
Running our harness across an entire fleet of repos revealed two lessons that only surfaced when this was done at scale.
First, deduplication is its own problem, big enough to need its own agents. When you are scanning a handful of repositories, you can manually eyeball overlapping bugs. Simple string matching or file-path checks won’t save you here. Determining whether two complex logic flaws are actually the exact same root bug sounds trivial, but it isn’t. It requires so much cognitive reasoning that we had to deploy dedicated Dedup agents just to clean up the noise, along with their own heuristics and ways of reducing the work.
The second is to not wire in static analysis early. We plumbed Semgrep all the way through, and the Hunters invoked it zero times in a month of runs. They would rather read and run the code. The wishlist, by contrast, was the single most-used tool in the system. It’s worth paying attention to what the agents actually reach for, rather than what you think they’ll want.
Making findings you can trust
The agent will edit the source code so its own exploit works, then triumphantly report the bug it just created. It will write a test that proves something entirely tautological like “exec() executes things, therefore critical vulnerability”. Or it builds an exploit that runs fine but proves nothing, because the threat model behind it is nonsense. If your harness doesn’t actively fight this, all you’ve built is a faster way to produce junk.
A Hunter has to state the threat model before it’s allowed to file anything. It has to define exactly who the attacker is, and what boundary the vulnerability crosses or what assumption it breaks. The output schema ordering enforces it. This requirement eliminates the vacuous findings, the “if a user has database write access, they can write to the database” kind.
Every confirmed finding ships with a PoC written as a test that runs against the original, untouched codebase. This prevents the agent from editing the source files to force an exploit to land. If there is no working PoC, we treat the finding as fake. In practice, that’s a Hunter compiling a thirty-line parsing loop, running it with memory protection enabled, and demonstrating that the incorrect read stride is originating from a stack address rather than the expected message body. You can re-run it yourself. Furthermore, every confirmed finding must also ship a proposed patch. What actually reaches our review queue is a verified bug, a working test, and a functional git diff, not just a vague text description of a problem.
Before an exploit path survives, deterministic code (written in plain code, not another model) mechanically verifies that the cited files and paths actually exist, and confirms that both the patch and the test parse correctly. This Validator cannot log findings of its own; its sole job is to aggressively disprove the Hunter‘s theory. If a Hunter is allowed to grade its own homework, it will confidently validate everything it outputs.
We don’t claim a false-negative rate for our system. There’s no labeled set of every real bug in a codebase, so any claimed recall number is entirely speculative. What we can watch is whether re-runs keep turning up new bugs (they do) and whether coverage is still growing across runs. It’s all a proxy, as you don’t know for sure how many bugs exist in a single codebase, but it’s a good-enough way of measuring effectiveness.
Stage 2: Vulnerability Validation System (VVS)
A finding coming out of the harness is just the start of the triage process, with all discoveries landing in a single, shared VVS that currently holds 13,841 findings across 145 repos in total. Triaging that volume is its own massive engineering problem, and it matters just as much as the hunting. That triage engine runs on a different model from the harness, broken down into three distinct jobs.
Agent/stage
Primary role
Spawns/ sub-agents/tooling
Dedup
Identifies if a vulnerability is already in the system, or raised as internal Jira ticket already
Deterministic: plain code builds inverted indexes over files, functions, trust boundaries, and rare tokens, then hands each finding a short candidate list
Probabilistic:Dedup agent reasons over that short list, Stable cross-run key reopens existing records
Judgment
Production reachability and validation
Single agent — builds context about the bug from MCP servers, to get the shape of what the service looks like in production. Searches the wiki, Jira, git, config, and all available other sources to try and understand whether a bug is truly applicable to our production environment, and then score the vulnerability against this. It also validates the bug against source code to understand if the bug still exists on the latest main branch.
Fixing
Generates patches, runs regression tests
Runs the regression test before and after (filtered to the affected test; full suite only when per-test filtering isn’t available). It requires a clean fail→pass flip on the target test to clear the gate. If the post-patch test fails, or if a global run detects downstream regressions, the commit is automatically blocked and flagged for human intervention.
Table 2: Vulnerability Validation System (VVS)
Deduping
Comparing every single finding against every other finding using an LLM scales at O(N^2), which falls apart completely at scale. To keep the model off the critical path, deterministic code builds inverted indexes over the structured data (touched files/functions, trust boundary, rare tokens) to generate a short list of real candidates. Only then does an agent look at that short list to see if a single fix would close several of them. Stable cross-run keys ensure re-found bugs reopen existing records rather than spawning new ones.
Contextual judgment
Judgment is a second, independent pass over what survived. The agent rechecks the latest information, pulling from deployment, environment, and config context to determine if the code path is reachable in prod, and identify the repo owner. This process filters “exploitable now” from “real but latent” and from “real but filed against the wrong component.” It’s moving a pile of chaotic findings into a risk-driven orchestration workflow.
Automated fixing
The Fixer takes the proposed patch and unit tests, rewrites them to match the repo’s style, applies the diff, and runs targeted tests. A clean fail→pass flip is the ideal and the only auto-cleanup case; a failing post-patch test blocks the commit. The Fixer never merges code on its own; a human must review the branch. This gate is the non-negotiable, human-in-the-loop safeguard that enables a clean, unbreakable cryptographic trail for change management compliance. Left to patch freely, a model will happily fix a security bug while quietly breaking an unrelated feature or adding dozens of new bugs.
Across all three triage jobs, each agent is confined to one narrow task wrapped in deterministic bookkeeping code, and nothing writes to production without a human signing off on a dry run. While this pipeline moves the engineering bottleneck from finding bugs to reviewing and landing fixes, the Fixer remains the youngest and slowest part of the system.
What it costs
Running hundreds of agents over a fleet of repos is not cheap, but at least the shape of the spend is predictable. Almost all of the compute budget goes directly into the hunt stage. This makes Gapfill our cost-to-coverage lever, as each additional pass costs roughly half as much as the initial hunt.
Because the cost per repository varies wildly, we budget per repo rather than per run. We enforce a strict task cap per repository and spin up a worker pool of anywhere from 50 to 200 workers. That way you can spend money on the repos that are actually finding things, and not waste it on the ones that aren’t.
It’s also why, for us, the big scans are a periodic backlog sweep and not a per-PR check. A full scan of a complex repo can take hours; the worst run took just over 14 hours. Cheaper, smaller harnesses are the right tool for that job.
How we tell it’s working
We measure our system’s effectiveness by tracking how efficiently our automated pipeline filters deliberate engineering noise into high-quality, actionable findings. Because we intentionally tune our Hunters to over-report subtle primitives that could be chained into larger attacks, our true indicator of success is how sharply we can refine that initial mountain of raw data, before it ever reaches a human.
To gauge this, we track exactly how many raw findings survive each validation stage over time. Thanks to better context injection from our Recon phase, our initial validation rejection rate dropped from 40% down to 11%, while the share of high-integrity findings climbed from 35% to 58% (representing ~12,057 lifetime findings).
Here’s the lifetime breakdown from raw candidates to actionable findings, at the point in time this blog post was written.
Vulnerability Discovery Harness (VDH)
Raw candidates: Everything the discovery harness emitted before independent validation.
Needs repro: Findings that appeared plausible but required manual reproduction before being trusted.
Rejected at validation: The validator disproved the threat model, exploit path, affected code, or evidence.
Duplicates: Candidates collapsed onto another finding from the same harness.
Survived validation: Findings that passed the independent validation gate and moved into the VVS.
Bugs that went elsewhere: Findings deliberately routed outside this flow.
Vulnerability Validation System (VVS)
Another vulnerability harness: Other automated sources feeding the same validation system.
Total bugs in system: The combined pool after ingest.
Duplicates: Findings the dedup pass identified as already covered by another canonical finding or ticket.
Wrong repo / other / not a risk: The noise bucket: misattributed findings, defense-in-depth, or latent risks.
Bugs sent to teams: Finalized, clean findings ready for remediation.
Judged Internet-exploitable: High-urgency findings a realistic attacker could trigger in production.
Not judged Internet-exploitable: Lower-urgency, actionable bugs (production issues, dependency risks, or config errors).
Final severity split: The categorization used to assign priority for the engineering teams.
The core metric of the harness isn’t a speculative recall score — it’s keeping the number of unconfirmed findings in front of real humans as close to zero as possible. The architecture needs to be a relentless filtering funnel.
Out of 20,799 raw candidates generated by VDH, only about 12,057 survived validation.
When these were pushed into the VVS, joining findings from another harness, the central pool was brought to 13,841.
The Dedup agent folded away 5,442 findings as duplicates.
1,154 were routed to the queue as ‘wrong-repo’ or ‘low-risk’ and were recycled back into the system where appropriate.
Ultimately this left 7,245 actionable findings for engineering teams to act on.
Traditional compliance rules dictate arbitrary remediation windows based entirely on a static CVSS score (e.g., “Fix all Highs in 30 days”). Our contextual judgment layer turns this compliance checkbox into actual risk management.
The architecture is capable of tracking findings back to their origin, meaning that fixing a single root cause resolves an entire cluster of findings rather than just patching individual issues. VDH system performance is also measured by dividing repos into (area x attack-class) cells and running the Gapfill agent iteratively until it stops producing findings. Whenever we update an underlying prompt, we test it against a held-out repository to see if that total coverage cell number actually moves.
The harness wires automated health signals to catch system failures early in the pipeline. If a hunt finished suspiciously fast and fails to spawn sub-hunts or gap tasks, it usually indicates a crashed dependency rather than a clean codebase. To remedy this, the system flags any Hunter agent that finishes with zero findings as “shallow” and immediately requeues it for a new run.
Finally, our system’s robustness is reinforced by the independent triage pass described earlier. By re-judging all submissions with a different model and separate logical weights, we ensure an unbiased, adversarial verification that is decoupled from the specific model used for discovery, providing a trust layer that persists regardless of which model is in use.
None of this is finished. We change our system constantly, and it is nowhere near a perfect science. But raw candidate findings are cheap now, and the only work worth doing is turning them into sound, verifiable code fixes.
Building your own harness means accepting that AI models are volatile, but your orchestration layer doesn’t have to be. By decoupling your security logic from any single provider, forcing adversarial verification, and automating your triage pipeline, you can turn a mountain of LLM noise into a reliable, fleet-wide defense engine.
Every codebase is a little different, so to show you how this actually works in the real world, we mapped out a realistic benchmark based on a standard repo run. Keep in mind that this represents a single pass on one repo; over time, as the continuous fleet-wide loop deduplicates, filters, and recycles findings, it reduces the volume of lifetime candidates by roughly 65%.
Engineering hours saved via automated patching: Rather than focusing on static baselines, we measure the health of our pipeline by its technical throughput, processing velocity, and its ability to eliminate the manual triage bottleneck:
Initial Validation Cut: For a standard repository (~30k lines of code), this yields 100 initial findings, with a full run taking 3-4 hours, maintaining a hyperfocused context window throughout.
Compression: The Deduplication and Contextual Judgment Layers process these candidates in parallel. Within 3 hours, the system compresses and refines the batch of findings from ~100 raw candidates to 80 distinct, high-fidelity bugs.
Remediation: The automated Fixer processes these 80 distinct bugs at an average rate of 5 minutes per bug. In total, the system can discover, validate, deduplicate, and open functional pull requests in approximately 14 hours.
Shrinking mean-time-to-resolve for critical flaws: Of course, you can’t dump 80 patches into production all at once without breaking things. To keep deployments safe, our system uses a tiered rollout:
Critical Exposure Containment: The system isolates the critical, high, and exploitable bugs (avg. 10 out of 80). We fast-track these for a human review and introduce them into release cycles, getting them fully patched in production in 5 days.
Incremental Hardening: The remaining latent risks, minor config anomalies, and lower-urgency bugs are incrementally rolled into prod over a 15-20 day window to guarantee platform stability.
How we’re handling all of this patching
These findings are the result of an isolated, ring-fenced research experiment designed to stress-test our code. They do not represent active, unpatched vulnerabilities in our live production environment.
Because the harness runs constantly in our test environments, these specific numbers are completely out of date by the time you’re reading this. Every single bug surfaced by the pipeline came attached to a working test case to demonstrate the bug and a draft patch. Our security teams are systematically processing the reports and applying the necessary fixes, meaning the Cloudflare products you use every day are already actively hardened against these vectors.
Along with this blog post, we’re releasing the initial skill we used to develop the harness, it’s been slightly cleaned up before release so it’s easier to understand and integrate, but the skill itself remains substantially the same. Hopefully the harness itself will follow shortly. This could be a starting point for your own vulnerability harness, your own skill, or whatever suits your needs best: github.com/cloudflare/security-audit-skill
If your team is working on the same problems and would like to compare notes, reach out to us at [email protected].
If you’re a user—owner?—of this cryptocurrency, this is important:
On May 29, the security researcher Taylor Hornby found a critical vulnerability in Zcash Orchard privacy pool using Claude Opus 4.8. The Zcash team hired Hornby specifically to look for this kind of issue. He found one fast enough to be embarrassing.
The Orchard pool is the newest and most advanced shielded transaction system in the cryptocurrency Zcash. Introduced in 2022, it allows users to send and receive ZEC while keeping transaction details private. It uses zero-knowledge proofs to validate transactions without revealing amounts or participants. The bug: a specific check that was supposed to validate transaction inputs wasn’t actually enforcing the rules it appeared to enforce. An attacker could have exploited the flaw to feed false inputs into that check and generate ZEC from nothing, with the zero-knowledge proof system blessing the fraudulent transaction as valid.
It’s fixed; that’s the good news. The bad news is that there’s no way of knowing if anyone exploited the vulnerability to steal money. And this fragility is the fundamental problem that makes blockchain such a bad idea.
In April, Anthropic initated Project Glasswing. The idea was to let companies use their new model to find and fix vulnerabilities in their own software. It was a fantastic PR move, and so many press outlets have uncritically parroted Anthropic’s claims that it’s now common wisdom that Mythos is better at finding software vulnerabilities than other models. Which is just nottrue.
In any case, Anthropic has published a Project Glasswing status report. It’s finding a lot of vulnerabilities in software—yay! Some of them are even dangerous. But almost none of them has been patched. It’s weird. There’s something fishy about the data that I don’t understand. That Anthropic refuses to release details—that it just says “trust us”—is a big problem here.
Abstract: Artificial intelligence is fundamentally reshaping the balance between vulnerability discovery and remediation. Frontier AI models are now capable of autonomously identifying exploitable software vulnerabilities at unprecedented speed and scale. This development exposes decades of accumulated technical debt created by a software industry that prioritized rapid deployment over secure-by-design engineering practices. Drawing on the evolution of software assurance, vulnerability disclosure frameworks, and U.S. cyber policy, this perspective argues that the current moment represents a strategic inflection point for governments, industry, and critical infrastructure operators. The author examines the growing tension between offensive and defensive equities in cyberspace, the emergence of AI-enabled vulnerability discovery capabilities in both the U.S. and China, and the increasing risks posed by unsupported legacy systems and AI-assisted code generation practices. Responsible disclosure can no longer remain a reactive or fragmented process, but must become a coordinated national and international resilience effort involving governments, software vendors, infrastructure operators, and emergency response organizations. The article concludes with an urgent call for accelerated remediation, large-scale patch management coordination, and sustained investment in automated vulnerability repair capabilities before adversaries exploit this rapidly narrowing window of opportunity.
Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.
The announcement requires context—but it contained an essential truth.
While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.
At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have othersparrot their claims?
Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.
Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.
But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.
Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.
But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.
Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.
Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.
Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.
As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.
The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.
AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.
The UK’s AI Security Institute evaluated GPT-5.5’s ability to find security vulnerabilities, and found that it is comparable to Claude Mythos. Note that the OpenAI model is generally available.
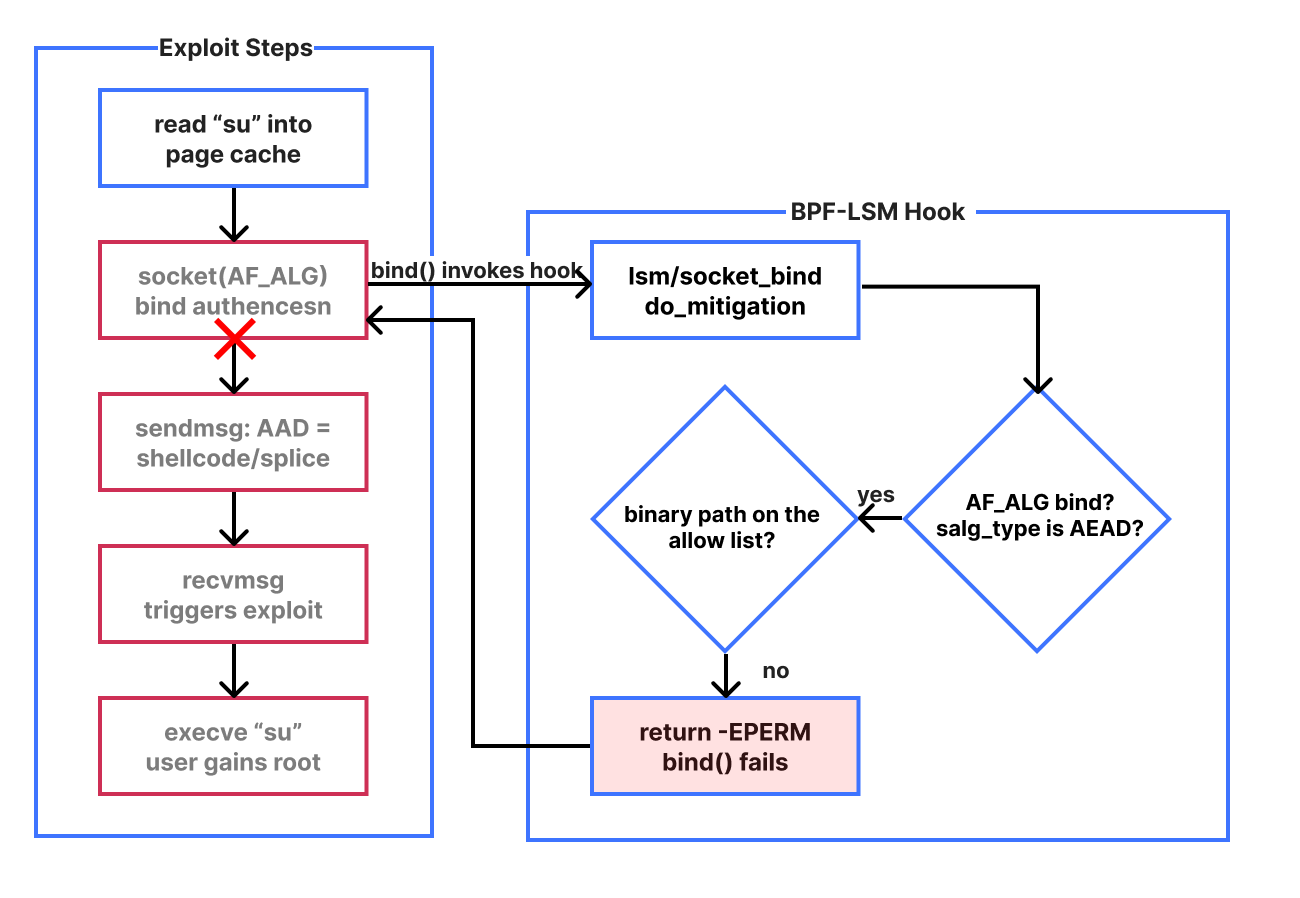
copy.fail is a Linux kernel local privilege escalation, not a browser or clipboard attack. Disclosed by Theori on 29 April 2026 with a working PoC.
It abuses the kernel crypto API (AF_ALG sockets) plus splice() to write four bytes at a time straight into the page cache of a file the attacker does not own.
The exploit works unmodified across Ubuntu, RHEL, Debian, SUSE, Amazon Linux, Fedora and most others. No race condition, no per-distro offsets.
The file on disk is never modified. AIDE, Tripwire and checksum-based monitoring see nothing.
Kubernetes Pod Security Standards (Restricted) and the default RuntimeDefault seccomp profile do not block the syscall used. A custom seccomp profile is needed.
The mainline fix landed on 1 April. Distros are rolling kernels out now. Patch.
“Local privilege escalation” sounds dry, so let me unpack it. It means: an attacker who already has some way to run code on the machine, even as the most boring unprivileged user, can promote themselves to root. From there they can read every file, install backdoors, watch every process, and pivot to other systems.
Why does that matter on shared infrastructure? Because “local” covers a lot of ground in 2026: every container on a shared Kubernetes node, every tenant on a shared hosting box, every CI/CD job that runs untrusted pull-request code, every WSL2 instance on a Windows laptop, every containerised AI agent given shell access. They all share one Linux kernel with their neighbours. A kernel LPE collapses that boundary.
On April 29, 2026, a Linux kernel local privilege escalation vulnerability was publicly disclosed under the name “Copy Fail” (CVE-2026-31431). Cloudflare’s Security and Engineering teams began assessing the vulnerability as soon as it was disclosed. We reviewed the exploit technique, evaluated exposure across our infrastructure, and validated that our existing behavioral detections could identify the exploit pattern within minutes.
There was no impact to the Cloudflare environment, no customer data was at risk, and no services were disrupted at any point. Read on to learn how our preparedness paid off.
Background
Our Linux kernel release process
Cloudflare operates a global Linux server infrastructure at an immense scale, with datacenters located across 330 cities. We maintain a custom Linux kernel build based on the community’s Long-Term Support (LTS) versions to manage updates effectively at this volume. At any given time, we may utilize multiple LTS versions from various series, such as 6.12 or 6.18, which benefit from extended update periods.
The community regularly merges and releases security and stability updates which trigger an automated job to generate a new internal kernel build approximately every week. These builds undergo testing in our staging data centers to ensure stability before a global rollout. Following a successful release, the Edge Reboot Release (ERR) pipeline manages a systematic update and reboot of the edge infrastructure on a four-week cycle. Our control plane infrastructure typically adopts the most recent kernel, with reboots scheduled according to specific workload requirements.
By the time a CVE becomes public knowledge, the necessary fix has typically been integrated into stable Linux LTS releases for several weeks. Our established procedures ensure that we have already deployed these patches.
At the time of the “Copy Fail” disclosure, the majority of our infrastructure was running the 6.12 LTS version, while a subset of machines had begun transitioning to the newer 6.18 LTS release.
About the Copy Fail vulnerability
It helps to understand the vulnerability before getting to the response story. A comprehensive write-up can be found in the original Xint Code disclosure post.
AF_ALG and the kernel crypto API
The Linux kernel’s internal crypto API manages functions like kTLS and IPsec. Userspace programs access this via the AF_ALG socket family, allowing unprivileged processes to request encryption or decryption. The algif_aead module facilitates this for Authenticated Encryption with Associated Data (AEAD) ciphers.
An unprivileged program follows these steps:
Opens an AF_ALG socket and binds to an AEAD template.
Sets a key and accepts a request socket.
Submits input via sendmsg() or splice().
Executes the operation using recvmsg().
The splice() system call is critical here, as it moves data by passing page cache references.
Memory mechanics: page cache and in-place crypto
The page cache is a shared system cache for file contents. Modifying a page belonging to a setuid binary effectively edits that program for all users until the page is evicted.
The crypto API utilizes scatterlists, which are structures linking various memory pages. In 2017, algif_aead was optimized for in-place operations, chaining destination and reference pages together. This design lacked enforcement to prevent algorithms from writing past intended boundaries.
The vulnerability: out-of-bounds write
When the user executes recvmsg(), the authencesn wrapper in the kernel performs a 4-byte write past the legitimate output region:
By using splice(), an attacker can chain a target file’s page cache pages to the scatterlist. The out-of-bounds write then taints the cached file, allowing an attacker to control which file is modified, the offset, and the specific 4 bytes written. This means the attacker can manipulate the following with this exploit:
File: Any readable file.
Offset: Tunable via assoclen and splice parameters.
Value: Controlled via AAD bytes 4-7 in sendmsg()
The exploit, step by step
The default exploit targets /usr/bin/su, a setuid-root binary present on essentially every distribution.
Cache Reference: Open /usr/bin/su as O_RDONLY and read() to populate the page cache. Use splice() on the file descriptor to pass these page cache references into the crypto scatterlist.
Setup: Create an AF_ALG socket, bind() to authencesn(hmac(sha256),cbc(aes)), set a key, and accept a request socket without needing privileges.
Write Construction: For each 4-byte shellcode chunk:
sendmsg() with AAD bytes 4–7 containing the shellcode.
splice() the binary into a pipe then the AF_ALG socket so assoclen + cryptlen targets the desired .text offset.
Trigger:recvmsg() initiates decryption. authencesn writes its scratch data to the target offset of /usr/bin/su in the page cache. Although the function returns -EBADMSG, the 4-byte write is now in the global page cache.
Execution: Running execve("/usr/bin/su") loads the tainted page cache. Since the binary is setuid-root, the injected shellcode executes with root privileges.
The upstream fix (commit a664bf3d603d) reverts the 2017 in-place optimization, removing the exploit.
How we responded
When the vulnerability was disclosed, many workstreams started in parallel:
Mapping the blast radius: Our security team worked with kernel engineers to determine which kernel versions were vulnerable and assess the potential exposure.
Validating coverage: Security reviewed the exploit technique and confirmed that our existing behavioral detections could identify the exploit pattern during authorized internal validation.
Proactive threat hunting: Security began searching for signs that the vulnerability had been exploited before it was publicly known, going back 48 hours in our fleet-wide logs.
Engineering a mitigation: Kernel engineers began building a runtime mitigation that would protect the fleet without breaking production services.
Continuing software updates: Our engineering teams worked on delivering an updated Linux kernel, which required carefully rebooting and rolling it out across our servers.
There was no customer impact at any point during this response.
Validating detection coverage
One of the first things our security team did was confirm that our existing endpoint detection would catch this exploit. Our servers run behavioral detection that continuously monitors process execution patterns. It doesn’t rely on knowing about specific vulnerabilities; it watches for anomalous behavior across the fleet.
When our engineers validated the vulnerability internally as part of the response, the detection platform flagged it within minutes. The system linked the entire execution chain—starting at the script interpreter, moving through the kernel’s cryptographic subsystem, and ending at the privilege escalation binary—flagging it as malicious based on fleet-wide behavioral patterns.
This happened without a signature update, without a rule change, and without human intervention. Our behavioral detection coverage existed before we wrote any custom logic for this particular Copy File exploit.
The confirmation was important because it meant we had coverage before writing a vulnerability-specific rule.
Hunting for exploitation
While our engineering team moved to a more targeted mitigation, our security investigation had been running since disclosure. This is our standard procedure for any critical vulnerability.
Our security team operates on a simple principle for critical vulnerabilities: assume compromise until you can prove otherwise. The investigation started from the assumption that exploitation could have occurred before the vulnerability was public, and we worked systematically to either confirm or rule it out.
The exploit leaves a distinctive trace in kernel logs when it runs. We searched for that trace across our centralized logging infrastructure, covering 48 hours before the vulnerability was publicly disclosed. If someone had exploited this before the world knew about it, we would have seen it.
We pulled access logs for affected systems and reconstructed who connected, when, and what commands they ran. This gave us a complete forensic picture of interactive activity on potentially affected infrastructure.
We checked that system binaries had not been tampered with, validated cryptographic hashes against known-good package manifests, looked for persistence mechanisms, and audited network connections for anything unusual. Everything was clean.
Incident timeline and impact
Time (UTC)
Event
2026-04-29 16:00
Copy Fail publicly disclosed.
2026-04-29 ~21:00
Security and Engineering teams began assessing fleet exposure and mitigation options before full declaration of the Incident Response process
2026-04-29 22:52
Security confirmed existing behavioral detection covered the Copy Fail exploit pattern. During authorized internal validation, detection flagged the activity within minutes.
2026-04-29 23:01
Existing behavioral detection generated a high-severity alert for exploit-like activity, confirming detection coverage for the technique.
2026-04-29 (evening)
First mitigation attempt pushed to our staging datacenter. The deployment process surfaced a dependency conflict; the mitigation was rolled back. No production systems were affected.
2026-04-29 (overnight)
Engineering drafted bpf-lsm mitigation program.
2026-04-30 03:14
Security incident declared to drive cross-functional collaboration and urgency. Security performed fleetwide threat hunting of historical data to confirm that no malicious activity was present on Cloudflare systems.
2026-04-30 (morning)
Engineering tested the bpf-lsm mitigation program and made it production-ready.
2026-04-30 14:25
Engineering incident declared to coordinate mitigation program and Linux patch rollout.
2026-04-30 ~17:00
Decision made: ship a patched build of the previous LTS line through reboot automation; do not accelerate the new LTS; lean on bpf-lsm in the meantime.
2026-04-30 (afternoon)
Visibility pipeline (eBPF tracing of AF_ALG socket usage) deployed fleet-wide. Gives a complete picture of all legitimate AF_ALG users.
2026-04-30 (evening)
bpf-lsm mitigation program rolled out behind a separate gate to fully mitigate the fleet. End-to-end verification on a previously-vulnerable test node confirms the exploit no longer works.
2026-05-04 (morning)
Reboot automation resumed at normal pace with the patched kernel.
2026-05-04 onward
Servers that had already passed through reboot automation earlier in the week manually rebooted to pick up the patched kernel. Unpatched servers update per our normal reboot automation.
This graph shows the progress of our mitigation program as it progressed through our infrastructure.
How did we mitigate it?
Because of the long timeframe involved in deploying a patched Linux kernel, we also pursued mitigating this exploit without a reboot.
Removing the module
The bug was in the algif_aead kernel module. Therefore, the simple fix was to just remove this module and disallow it from being reloaded.
This mitigation was therefore exactly what the Copy Fail write-up from the security researchers who identified it recommends.
Unfortunately removing the module would have impacted software that leverages the kernel crypto API. This meant that we had to figure out a more surgical mitigation.
Bpf-lsm
We’ve already developed and deployed such a tool for this exact scenario: bpf-lsm. Instead of removing the module, this tool leaves it loaded for legitimate users and uses a BPF Linux Security Module program to deny the socket_bind LSM hook for everyone else. This completely blocks the front door for any exploits.
A draft of the eBPF program was put together overnight. Team members picked it up the following morning, ran validations, and made it production-ready. The program is fairly straightforward. On every socket_bind call:
If the socket family is not AF_ALG, allow the call through unchanged.
If the family is AF_ALG, check the calling binary’s path against an allow-list of the binaries we know to be legitimate users.
If the binary is on the allow-list, allow the bind. Otherwise, deny it.
To verify the mitigation on a given machine without exploiting it, the Copy Fail write-up gives a one-liner:
python3 -c 'import socket; s = socket.socket(socket.AF_ALG, socket.SOCK_SEQPACKET, 0); s.bind(("aead","authencesn(hmac(sha256),cbc(aes))"));'
On a mitigated machine you get PermissionError: [Errno 1] Operation not permitted (or FileNotFoundError, depending on which mitigation is active) instead of a successful bind.
Rolling it out
Before enabling enforcement, we verified that our known internal service was the sole legitimate AF_ALG user to avoid accidental outages. We used prometheus-ebpf-exporter to hook the socket() syscall and track AF_ALG usage per binary across the fleet. This required no kernel changes and provided aggregate data from hundreds of thousands of servers within hours. Results confirmed the identified service was indeed the only legitimate user.
So the bpf-lsm rollout was deliberately staged in two steps:
Get visibility first. Push the ebpf-exporter config gated by salt. Confirm at the metric layer that the known service is effectively the only thing creating AF_ALG sockets.
Then enforce. Push the bpf-lsm program behind a separate enforcement gate.
In parallel, the upstream backport for our majority LTS line finally became available, and our internal automation built a patched kernel against it.
We started to test the patched kernel in our staging datacenters as soon as possible, then we resumed the longer reboot process in order to fully patch our fleet.
Remediation and follow-up steps
While we were prepared for this scenario, at Cloudflare we’re always learning and improving. Key areas we identified for improvement:
Better visibility into kernel-API dependencies. We will review kernel-subsystem usage across production services, so we can continue to quickly mitigate exploits without service disruption.
Better runtime mitigation. bpf-lsm is a valuable tool for mitigations, but we want to make this tool even better. This will include looking into faster deployments, better playbooks, and better logging and visibility of the tool.
Reduce attack surface of Linux Kernel. Review and audit our kernel configuration. Proactively identify unused modules or features so that we can remove them from our build entirely.
Conclusion
The “Copy Fail” vulnerability presented a unique challenge for us. Despite our practice of deploying Linux patch updates every two weeks, we remained vulnerable because a month-old mainline fix had yet to be backported to our primary kernel line. Despite that, we were still able to roll out patched kernels within hours of the backport’s release. In the interim, bpf-lsm provided a surgical, no-reboot mitigation that secured our fleet. While our initial attempt to disable the problematic module failed, it did so safely within our internal staging environment rather than production, allowing us to identify this dependency.
By the end of the rollout, every machine in our fleet was protected by either a patched kernel or a bpf-lsm program denying the vulnerable code path to non-allow-listed binaries. There was no customer impact at any point during this incident, and we have committed to the follow-up work above to make our response faster and our visibility better the next time something like this lands. Responsible disclosure works, in-kernel visibility tooling pays off in moments exactly like this one, and bpf-lsm continues to be one of the most useful primitives we have for runtime kernel mitigation.
At Cloudflare, critical vulnerability response is a coordinated effort across Security, Engineering, Product, and many other teams. Special thanks to Ali Adnan, Ivan Babrou, Frederik Baetens, Curtis Bray, Piers Cornwell, Everton Didone Foscarini, Rob Dinh, Elle Dougherty, Kevin Flansburg, Matt Fleming, Kimberley Hall, Brandon Harris, Jerry Ho, Oxana Kharitonova, Marek Kroemeke, Fred Lawler, James Munson, Nafeez Nazer, Walead Parviz, Miguel Pato, Evan Pratten, Josh Seba, June Slater, Ryan Timken, Michael Wolf, Jianxin Zeng and everyone else who contributed to the investigation, mitigation, and remediation of Copy Fail. We’d also like to thank the Linux upstream maintainers and Copy Fail researchers whose work helped make a rapid response possible.
DarkSword is a sophisticated piece of malware—probably government designed—that targets iOS.
Google Threat Intelligence Group (GTIG) has identified a new iOS full-chain exploit that leveraged multiple zero-day vulnerabilities to fully compromise devices. Based on toolmarks in recovered payloads, we believe the exploit chain to be called DarkSword. Since at least November 2025, GTIG has observed multiple commercial surveillance vendors and suspected state-sponsored actors utilizing DarkSword in distinct campaigns. These threat actors have deployed the exploit chain against targets in Saudi Arabia, Turkey, Malaysia, and Ukraine.
DarkSword supports iOS versions 18.4 through 18.7 and utilizes six different vulnerabilities to deploy final-stage payloads. GTIG has identified three distinct malware families deployed following a successful DarkSword compromise: GHOSTBLADE, GHOSTKNIFE, and GHOSTSABER. The proliferation of this single exploit chain across disparate threat actors mirrors the previously discovered Coruna iOS exploit kit. Notably, UNC6353, a suspected Russian espionage group previously observed using Coruna, has recently incorporated DarkSword into their watering hole campaigns.
A week after it was identified, a version of it leaked onto the internet, where it is being used more broadly.
This news is a month old. Your devices are safe, assuming you patch regularly.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.