Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=Ul0tDc-2XNw
[$] Fedora change aims for 99% package reproducibility
Post Syndicated from jzb original https://lwn.net/Articles/1014979/
The effort to ensure that open-source software is reproducible has been
gathering steam over the years, and gaining traction with major Linux
distributions. Debian, for example, has been working toward reproducible
builds for more than a decade; it can now
produce official
live CDs of the current stable release that are
reproducible. Fedora started on the path much later, but it has
progressed far enough that the project is now considering a change
proposal for the Fedora 43 development cycle, expected to be
released in October, with a goal of
making 99% of Fedora’s package builds reproducible. So far, reaction
to the proposal seems favorable and focused primarily on how to
achieve the goal—with minimal pain for packagers—rather than whether to attempt it.
Security updates for Monday
Post Syndicated from jake original https://lwn.net/Articles/1015968/
Security updates have been issued by Debian (amd64-microcode, flatpak, intel-microcode, libdata-entropy-perl, librabbitmq, and vim), Fedora (augeas, containerd, crosswords-puzzle-sets-xword-dl, libssh2, libxml2, nodejs-nodemon, and webkitgtk), Red Hat (libreoffice and python-jinja2), SUSE (389-ds, apparmor, corosync, docker, docker-stable, erlang26, exim, ffmpeg-4, govulncheck-vulndb, istioctl, matrix-synapse, mercurial, openvpn, python3, rke2, and skopeo), and Ubuntu (ansible, linux, linux-hwe-5.4, linux-azure, linux-azure-5.4, linux-bluefield, linux-gcp, linux-gcp-5.4,
linux-ibm, linux-kvm, linux-oracle, linux-oracle-5.4, linux-xilinx-zynqmp, linux-azure-fips, linux-gcp-fips, linux-fips, linux-fips, linux-aws-fips, linux-azure-fips, linux-gcp-fips, linux-nvidia-tegra, linux-nvidia-tegra-igx, linux-realtime, linux-intel-iot-realtime, linux-xilinx-zynqmp, opensc, and ruby-doorkeeper).
Adopting Amazon Q Developer in Enterprise Environments
Post Syndicated from Rene-Martin Tudyka original https://aws.amazon.com/blogs/devops/adopting-amazon-q-developer-in-enterprise-environments/
Increasing developer productivity has been a persistent challenge for senior leaders over the past decades. With the rise of generative artificial intelligence (AI), a new wave of innovation is transforming how software teams work. Generative AI tools like Amazon Q Developer are emerging as game-changers, supporting developers across the entire software development lifecycle. But how are large-scale organizations successfully adopting this AI-assisted approach? This document shares good practices I have discovered through working with enterprise customers navigating this technological transformation.
A common misperception still is that a developer is more productive when they write code faster. But a median developer spends less than one hour per day writing code, as a study conducted by software.com in 2022 shows. This makes clear that there are other aspects to consider when it comes to building an application and running it in production. Generative AI tools for developers, such as Amazon Q Developer, started as coding companions that provided inline completions. As the technology evolved, Amazon Q Developer is now able to support developers across the entire software development life cycle.
The Change Challenge
Generative AI offers new and interesting ways for developers to solve challenges and to support them in their daily work. But taking advantage of those opportunities takes some time. It introduces a noticeable change to their familiar ways of working and therefore it is much about forming a new habit. This, according to science, usually takes a minimum of two months. Teams need the space and permission to play with this new approach and to find out what works best for them. Expecting them to adopt a new way of working while expecting the same (or higher) level of output at the same time will only lead to teams falling back to what they know works. For customers that successfully have adopted Amazon Q Developer I have seen them reducing the delivery expectations to give space to learn, and having required teams to share learnings in return.
Additionally, as in any other large change project there is a significant cultural aspect to consider. If people feel intrinsically convinced by the value and benefits of an AI-supported approach to software engineering they will use it. “Simply ordering from above” will not help making an adoption successful. But building community, experimenting, learning, and sharing successes will. “Culture eats strategy for breakfast”, as the management visionary Peter Drucker said.
Keeping that in mind it is clear that there is no one-size-fits-all prescriptive way of successfully introducing generative AI tools for developers in your organization. It very much depends on your individual culture, goals, challenges, people, skills, and technology stack for example. However, there are a number of principles and good practices that work well with several of our large-scale customers who have successfully adopted Amazon Q Developer.
Best Practices for Successful Adoption
The following illustration describes the change management cycle and recommended activities for adopting AI-assisted software development.

Figure 1. The change management cycle
1. Secure Top-Down Commitment
Secure executive buy-in for adopting AI-assisted software development because this is a powerful sign for the organization. It helps to remove roadblocks and to promote successes across the organization. An executive sponsor links the adoption of AI-assisted software development to the strategic goals of the organization, will help resolving prioritization and capacity conflicts. Invite the sponsor to a kick-off meeting. Include them for the discussion of goals and success criteria, and keep them updated on progress, success stories, and challenges.
2. Become Clear on Goals and Success Criteria
Simply rolling out Generative AI tools to a large developer base won’t be enough. You need to be clear what you expect from such an adoption for your organization, for your developers, and for your business. It is important for you to understand your organization’s pain points from a developer experience perspective and how they affect your development productivity. These likely differ between different personas, like Software Developers and DevOps Engineers. For example, are your applications lacking test coverage or is your code lacking documentation, which creates a maintenance burden, and makes it difficult to onboard new developers? Is handling legacy code risky and time-consuming so that you avoid necessary upgrades because of the complexity and effort? Is troubleshooting applications locally or in production eating up your developers’ time? Or are you facing challenges caused by hard-to-find security issues in the code? What is it that you want to achieve by introducing an AI-assisted development approach, and why?
3. Establish Ownership
Adopting a new approach like the use of generative AI in software development at scale leads to many change management and coordination tasks. Those are related to getting access to the tool, enablement for new users, budget planning, measuring success and creating transparency on problems, creating momentum and making sure the adoption sustains, amongst others. Therefore, introducing a Customer Champion as a leader who coordinates the business and technology related aspects of the adoption is a common approach. They will connect the strategic goals of the organization with the tactical activities necessary for the implementation. If your adoption is spanning multiple different business units with larger developer bases consider establishing this role for each of them, forming a team that collaborates across your whole organization. Key responsibilities of the Customer Champion are to bring the right people together to successfully work on the adoption, to create transparency on status, and to address impediments early on.
4. Introduce Metrics
Once you have gained clarity on the specific pain points and goals for your organization, the next step is to determine the appropriate metrics to measure the success of your efforts. For example, you can measure the impact of using Amazon Q Developer on onboarding new developers by tracking the time to first commit against a previously established baseline average. Comparing the time it takes to complete certain tasks – like writing and integrating code, fixing bugs, setting up or upgrading environments, the time it takes to build a new feature, or by comparing sprint velocity before and after the introduction of Amazon Q Developer will give you further indications. But keep in mind that there is ambiguity in these metrics because they are impacted by different factors.
Focusing on developer experience and productivity, monitor the development of your established measurement framework, like DORA, SPACE, or GSM. SPACE in particular, with its “Satisfaction & Well-Being” dimension, pays close attention to how software developers perceive their work and how satisfied they are with their own productivity. Tools like Amazon Q Developer have shown a positive effect here, as for example a McKinsey study shows. They help to free developers from tasks that are perceived as toil, like repetitive and boring grunt work that doesn’t necessarily bring business value. To measure this impact on perceived productivity, customers sometimes design simple surveys, asking developers questions like “in percentage, how would you estimate the impact of using Amazon Q Developer on your productivity” or “on a scale from 1-5, how is Amazon Q Developer impacting the satisfaction with your day-to-day work?”
As a last dimension, understanding the general usage of Amazon Q Developer across your organization is important. Monitor the number active subscriptions, accepted code recommendations, or the number of executed security scans from the Amazon Q Developer dashboard. That way you will get an understanding for the acceptance of the tool in your developer base. Correlate this information with the success metrics you defined.
5. Start Small
When “rolling out” an AI-assisted software development approach, keep the technology adoption lifecycle and Everett Roger’s bell curve in mind. It describes that adoption of a new technology usually starts with a few “innovators”, followed by a small fraction of “early adopters”. Only if those early groups demonstrate convincing success, the majority of users will follow the adoption. To settle on this model will help you making the adoption of AI-assisted development successful in your organization.
Start small. Identify your tech innovators, or champions, who are enthusiastic to support the introduction of Amazon Q Developer and to advocate the approach in your organization. With them, build a team or a Center of Excellence (COE) that will help with identifying early adopters across your development teams, building technical and enablement foundations for onboarding users, creating roll-out plans, and evangelizing and sustaining the adoption. The champions will act as a bridge between your adoption program team and your users. They can provide insights and feedback on the adoption and come up with recommendations.
6. Create Momentum
Now that you have your foundations in place it is time to create momentum and onboard your early adopters to Amazon Q Developer. Start with a communication plan to raise awareness, to share updates and success stories, and to collect feedback from the users. You will need to create training material covering organization-specific resources (how to get access, for example, or which communication channels and contact points exist), user guides, tutorials, and pointers to relevant documentation and online resources. Consider creating your own prompt library, documenting prompts for Amazon Q Developer that your users find particularly helpful. There are community projects like promptz.dev that can deliver inspiration. Especially for new users this will have a lot of value for getting up to speed.
Consider how to integrate learning pathways with your organization’s learning platform moving forward. These should include the company-specific experience and knowledge you collect. In addition, it might be helpful to integrate external offers, like classroom trainings or workshop formats offered by AWS.
Hands-on technical enablement workshops will help your early adopters jumpstarting their experience. AWS offers multiple formats that can be tailored to your individual context. These include service deep-dives with Amazon Q Developer specialists, Immersion Days and hackathon support for teams to hands-on experience the tool in a guided, interactive format, or joined proof-of-value engagements. Your AWS account team will provide you more information.
7. Sustain and Scale Adoption
At that point you will have established Amazon Q Developer among an initial segment of your developer base. However, keeping Roger’s adoption curve in mind the largest part of the adoption still lies ahead of you. To facilitate the it across your whole organization, focus on delivering enablement workshops for the teams to be onboarded. These will be led by your champions and incorporate your organization-specific practices and knowledge.
To sustain the adoption, make sure the existing user base stays active. Continue offering exchange and support, collecting feedback, updating your enablement material, sharing updates on the latest developments for Amazon Q Developer, and reviewing your metrics. Create visibility across your organization for the accomplishments and positive experiences. Let user talk about the impact Amazon Q Developer has on their work. This will help building momentum. Nurture community building around your users of AI-assisted development.
Establish regular office hours with your champions for providing support and enablement to your users of Amazon Q Developer. This will facilitate the continuous gathering of feedback to improve documentation and enablement materials, collect and promote success stories, and validate the adoption approach. Additionally, establish a consistent communications and reporting cadence to keep all relevant stakeholders informed of key metrics, updates, feedback, and success stories. This ensures the alignment of the adoption of AI-assisted development with your strategic goals and expectations.
8. Inspect and Adapt
In addition, keep reflecting on the goals and metrics you came up with from a strategic perspective. Are they developing in the right direction? Are your pain points still the same? Should you move your focus to different aspects of the software development life cycle? And how might new capabilities of Amazon Q Developer support your goals?
Conclusion
By following the outlined approach, large organizations can successfully navigate the challenges of adopting Amazon Q Developer. The approach addresses technical, cultural, and organizational aspects of the adoption, increasing the likelihood of realizing the full potential of AI-assisted development across the enterprise.
If you are looking for advice or support during your adoption journey, your AWS Account Team will connect you with experts on Amazon Q Developer, provide you information on training and enablement, and support you with setting up a successful rollout program for your organization. To learn more about how Amazon Q Developer’s capabilities support the whole software development lifecycle, visit the product page or have a look at the documentation.
About the Author
Rene-Martin Tudyka is a Senior Customer Solutions Manager at AWS and provides guidance and support for enterprise customers on their cloud maturity journey. He has a long background in developing highly performant IT organizations and in successful large-scale cloud adoption.
Seeing is Securing: MDR VALUE at-a-glance with the Detection and Response Dashboard
Post Syndicated from Conner Goldstein original https://blog.rapid7.com/2025/03/31/seeing-is-securing-mdr-value-at-a-glance-with-the-detection-response-dashboard/
Transparency is core to Managed Detection & Response (MDR). It’s necessary between Rapid7 and our customers as we conduct security operations on their behalf. And it’s necessary for our customers to communicate transparently and effectively with their stakeholders.
Scroll on – because there’s a new executive-level MDR performance dashboard that delivers it.
Just the right amount of information
Every day, our four global SOCs analyze and triage thousands of alerts – investigating incidents, informing remediation actions, and quarantining breached endpoints. This activity is then translated into strategic guidance by dedicated Cybersecurity Advisors, ensuring security leaders have the insights they need to stay ahead of threats.
To deliver on that commitment to transparency, we ensure that all of this activity takes place in InsightIDR, our next-gen SIEM and XDR platform that gives MDR customers a direct line of sight into security activity, logs, detections, and their security posture. You see what the SOC sees – every detection, alert, investigation, and response action across your environment.
To keep pace with the speed of modern adversaries and realize the value of their MDR program, security teams need a high-level, executive-ready snapshot that showcases program effectiveness, surfaces key trends, and enables informed decision-making.
Enter the Detection and Response Dashboard

A holistic view of your MDR program
The Detection and Response Dashboard provides a clear, high-level snapshot of your entire MDR program. The customizable and downloadable summary visualizes key metrics, helping teams quickly identify risks, trends, and security outcomes.
Clarity on How the SOC is Working for You
Designed to give security teams an at-a-glance understanding of how their MDR program is performing – breaking down everything from SOC activity and detection trends to response times and containment actions – the Dashboard distills the thousands of alerts and SOC activity that I mentioned earlier.
Offering a transparent lens into the day-to-day operations of Rapid7’s global SOCs, customers are given confidence in the behind-the-scenes work driving their MDR program. Instead of wondering whether threats are being seen or how decisions are made, customers can see the operational heartbeat of their service: what’s being triaged, when the SOC steps in, and how investigations unfold over time. This level of visibility helps customers trace the lifecycle of real threats through the eyes of the SOC — from detection to action — while also revealing patterns in analyst activity, responsiveness, and escalation. It bridges the gap between outsourced operations and internal accountability, allowing security teams to not only report on what’s being done, but understand how it’s being done and why.
Visualize and Understand Threat Trends Over Time
Threats don’t just appear and disappear – they evolve, shifting tactics and targeting different areas of your environment. The Detection and Response Dashboard surfaces key trends in the alerts and investigations processed by the SOC, mapping out attacker behaviors and identifying the most frequently targeted assets. By tracking how threats develop and where adversaries are focusing their efforts, security teams can better anticipate emerging risks and validate the impact of their security investments.
Security teams can use view and download summary information including:
- Threat Prioritization & Alert Trends: Analyze the volume of alerts by severity and identify the most common alert types to understand the highest-risk threats.
- Incident Response Efficiency: Threat pipeline visualization tracks how alerts progress to investigations and incidents, while mean time to begin investigating highlights response speed.
- Investigation & Resolution Metrics: Insights into closed alerts and investigations by priority and disposition help teams assess the effectiveness of their threat response and remediation efforts.
For highly mature security teams, this level of insight offers a data-driven foundation for evolving defenses and prioritizing resources based on real-world threat activity. At the same time, the Dashboard remains accessible for teams earlier in their security journey, providing a clear, digestible view of security trends without overwhelming technical detail.
Demonstrate Your Security Program’s Value Internally
Proving the impact of a security program isn’t just about responding to threats – it’s about showcasing measurable progress. The Detection and Response Dashboard translates raw security data into compelling, digestible visuals, making it easier to communicate security performance to stakeholders at all levels.
By presenting security outcomes in a way that resonates across both technical and executive audiences, the Dashboardenables teams to align more effectively with IT and business leaders. This ensures that security investments and priorities are grounded in real data, not assumptions. And as MDR customers expand their security programs, integration with Asset Discovery allows teams to identify hidden assets and weave risk-aware insights directly into their broader security strategy.
The Next Step of ‘Seeing is Securing’ is Here
It’s now easier than ever to understand, track, and communicate the full scope and value of your security operations through your partnership with the Rapid7 SOC. If you’re not yet leveraging our MDR, you’re missing out on the most comprehensive approach to 24/7 SOC expertise, risk-aware threat detection, and unlimited incident response. Learn more about how Rapid7 MDR can strengthen your security program – get the details here.
Sinking of the Tanker T. C. McCobb
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=HvjzU_qh_ow
The Signal Chat Leak and the NSA
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/03/the-signal-chat-leak-and-the-nsa.html
US National Security Advisor Mike Waltz, who started the now-infamous group chat coordinating a US attack against the Yemen-based Houthis on March 15, is seemingly now suggesting that the secure messaging service Signal has security vulnerabilities.
"I didn’t see this loser in the group," Waltz told Fox News about Atlantic editor in chief Jeffrey Goldberg, whom Waltz invited to the chat. "Whether he did it deliberately or it happened in some other technical mean, is something we’re trying to figure out."
Waltz’s implication that Goldberg may have hacked his way in was followed by a report from CBS News that the US National Security Agency (NSA) had sent out a bulletin to its employees last month warning them about a security "vulnerability" identified in Signal.
The truth, however, is much more interesting. If Signal has vulnerabilities, then China, Russia, and other US adversaries suddenly have a new incentive to discover them. At the same time, the NSA urgently needs to find and fix any vulnerabilities quickly as it can—and similarly, ensure that commercial smartphones are free of backdoors—access points that allow people other than a smartphone’s user to bypass the usual security authentication methods to access the device’s contents.
That is essential for anyone who wants to keep their communications private, which should be all of us.
It’s common knowledge that the NSA’s mission is breaking into and eavesdropping on other countries’ networks. (During President George W. Bush’s administration, the NSA conducted warrantless taps into domestic communications as well—surveillance that several district courts ruled to be illegal before those decisions were later overturned by appeals courts. To this day, many legal experts maintain that the program violated federal privacy protections.) But the organization has a secondary, complementary responsibility: to protect US communications from others who want to spy on them. That is to say: While one part of the NSA is listening into foreign communications, another part is stopping foreigners from doing the same to Americans.
Those missions never contradicted during the Cold War, when allied and enemy communications were wholly separate. Today, though, everyone uses the same computers, the same software, and the same networks. That creates a tension.
When the NSA discovers a technological vulnerability in a service such as Signal (or buys one on the thriving clandestine vulnerability market), does it exploit it in secret, or reveal it so that it can be fixed? Since at least 2014, a US government interagency "equities" process has been used to decide whether it is in the national interest to take advantage of a particular security flaw, or to fix it. The trade-offs are often complicated and hard.
Waltz—along with Vice President J.D. Vance, Defense Secretary Pete Hegseth, and the other officials in the Signal group—have just made the trade-offs much tougher to resolve. Signal is both widely available and widely used. Smaller governments that can’t afford their own military-grade encryption use it. Journalists, human rights workers, persecuted minorities, dissidents, corporate executives, and criminals around the world use it. Many of these populations are of great interest to the NSA.
At the same time, as we have now discovered, the app is being used for operational US military traffic. So, what does the NSA do if it finds a security flaw in Signal?
Previously, it might have preferred to keep the flaw quiet and use it to listen to adversaries. Now, if the agency does that, it risks someone else finding the same vulnerability and using it against the US government. And if it was later disclosed that the NSA could have fixed the problem and didn’t, then the results might be catastrophic for the agency.
Smartphones present a similar trade-off. The biggest risk of eavesdropping on a Signal conversation comes from the individual phones that the app is running on. While it’s largely unclear whether the US officials involved had downloaded the app onto personal or government-issued phones—although Witkoff suggested on X that the program was on his "personal devices"—smartphones are consumer devices, not at all suitable for classified US government conversations. An entire industry of spyware companies sells capabilities to remotely hack smartphones for any country willing to pay. More capable countries have more sophisticated operations. Just last year, attacks that were later attributed to China attempted to access both President Donald Trump and Vance’s smartphones. Previously, the FBI—as well as law enforcement agencies in other countries—have pressured both Apple and Google to add "backdoors" in their phones to more easily facilitate court-authorized eavesdropping.
These backdoors would create, of course, another vulnerability to be exploited. A separate attack from China last year accessed a similar capability built into US telecommunications networks.
The vulnerabilities equities have swung against weakened smartphone security and toward protecting the devices that senior government officials now use to discuss military secrets. That also means that they have swung against the US government hoarding Signal vulnerabilities—and toward full disclosure.
This is plausibly good news for Americans who want to talk among themselves without having anyone, government or otherwise, listen in. We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.
Because of the Signal chat leak, it’s less likely that they’ll use vulnerabilities in Signal to do that. Equally, bad actors such as drug cartels may also feel safer using Signal. Their security against the US government lies in the fact that the US government shares their vulnerabilities. No one wants their secrets exposed.
I have long advocated for a "defense dominant" cybersecurity strategy. As long as smartphones are in the pocket of every government official, police officer, judge, CEO, and nuclear power plant operator—and now that they are being used for what the White House now calls calls "sensitive," if not outright classified conversations among cabinet members—we need them to be as secure as possible. And that means no government-mandated backdoors.
We may find out more about how officials—including the vice president of the United States—came to be using Signal on what seem to be consumer-grade smartphones, in a apparent breach of the laws on government records. It’s unlikely that they really thought through the consequences of their actions.
Nonetheless, those consequences are real. Other governments, possibly including US allies, will now have much more incentive to break Signal’s security than they did in the past, and more incentive to hack US government smartphones than they did before March 24.
For just the same reason, the US government has urgent incentives to protect them.
This essay was originally published in Foreign Policy.
Tasers & Excited Delirium: Last Week Tonight with John Oliver (HBO)
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=7Yd9nLQx3qQ
S12 E06: Signalgate, Immigration Arrests & Tasers: 3/30/25: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=R-NHkonDsok
Invention of the "Interceptor."
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=O2HLGJvitUA
Orogeny
Post Syndicated from xkcd.com original https://xkcd.com/3070/
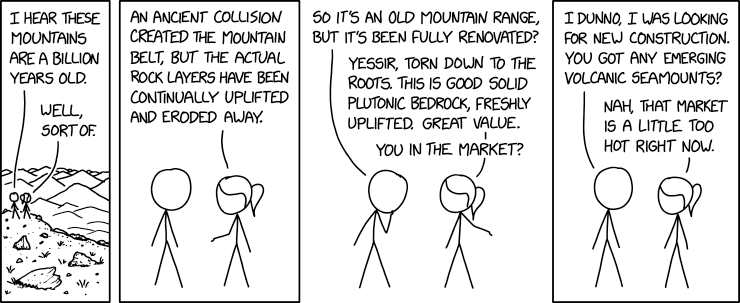
Renewable energy means we can stop setting money on fire, silly billy
Post Syndicated from Technology Connextras original https://www.youtube.com/watch?v=Y2qSaD1v4cQ
STH Q1 2025 Letter from the Editor Re-calibration and Expansion
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/sth-q1-2025-letter-from-the-editor-re-calibration-and-expansion/
In the STH Q1 2025 Letter from the Editor, we go behind-the-scenes at STH and talk about what we have been working on
The post STH Q1 2025 Letter from the Editor Re-calibration and Expansion appeared first on ServeTheHome.
Comic for 2025.03.30 – The Flash
Post Syndicated from Explosm.net original https://explosm.net/comics/the-flash
New Cyanide and Happiness Comic
Stepmother
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/stepmother/


The Mark 17 Thermonuclear Bomb
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=KVVc1uMvYos
The Crucial 128GB DDR5-5600 SODIMM Kit We Are Using in Mini PCs
Post Syndicated from John Lee original https://www.servethehome.com/the-crucial-128gb-ddr5-5600-sodimm-kit-we-are-using-in-mini-pcs/
These Crucial 64GB DDR5-5600 SODIMMs come in pairs for 128GB in the kit allowing for more memory in mini PCs (and notebooks)
The post The Crucial 128GB DDR5-5600 SODIMM Kit We Are Using in Mini PCs appeared first on ServeTheHome.
Four stable kernel updates
Седмицата (24–29 март)
Post Syndicated from Надежда Радулова original https://www.toest.bg/sedmitsata-24-29-mart/

41 по-голямо ли е, или е по-малко от 35? Това е задачка за първокласник и отговорът е еднозначен. Освен ако, разбира се, не докопаш грешните топки. Е, тогава се оказва, че си в друг номер и само си мислиш, че джуркаш тото топки, а всъщност вадиш зайче от шапка. Но вместо зайче – куку! – излиза Пеевски. Така да се каже, кой друг да излезе от шапката, пардон, от сферата с тотото?! Та то му е родно… И е редно да размаха пръст, защото в тази сфера по-добра от мама няма!
Изобщо, темата с „грешните топки“ се оказва водеща тази седмица. Високопоставени служители на президентската администрация в САЩ разнообразили седянката си, като открехнали вратата и – без сами да разберат как – поканили и главния редактор на The Atlantic Джефри Голдбърг. И това, докато обсъждали строго секретни военни атаки срещу хутите в Йемен. Грешка! За капак Тръмп коментира, че не харесвал особено The Atlantic. Ех, значи… Единственото, което мога да посъветвам тези мъдри държавни мъже, е следващия път да поканят на седянката и Пеевски.
Ехо, къде без него?! Та у нас вече открито се говори за „правителството на Пеевски“. Пийте един деган, преди да прочетете седмичния вътрешнополитически обзор на Емилия Милчева – не вземете ли таблетката, свят ще ви се завие и ще ви се доповръща. В „Марш на скок за още власт за ГЕРБ“ новите назначения в регулаторите само досипват в угодните на ГЕРБ и Пеевски порции власт, опозицията е шизо, а на всичкото отгоре може да се окаже, че европрокурорката Теодора Георгиева е играла Снежанка в „Осемте джуджета“, и то в компанията на джуджето Худини, известно като Пепи Еврото.
Пак по темата за „топките“ – поредни две български шпионки, част от руска шпионска мрежа, са разследвани и разкрити от Би Би Си. Цветелина Генчева и Цветанка Дончева са провеждали операции за наблюдение, подпомагащи дейността на наскоро заловените и осъдени за шпионаж в Лондон шестима българи. От снимките на Цветелина и Цветанка, от публикациите на техни познати и от самото разследване оставаме с впечатлението, че „момичетата на Марсалек“ нямат много общо с „момичетата на Бонд“ и всъщност са доста „ниски топки“. Тюх, да му се не види! Не били компютри, а компоти, не били шпионки, а пионки.
И така, тупайки топката все по-ниско, преминаваме към игра в центъра на терена. „В центъра на терена“ у нас означава даден въпрос – като например мизогинното и направо човеконенавистно питане „Допустимо ли е жена да кърми на работното си място?“, пък било то и в пленарната зала – периодично да се превръща в социална дъвка. Ад. Имам чувството, че живеем в оня филм с Бил Мъри и всеки ден се събуждаме с все същия отново неразрешен проблем, в трепетно очакване мармотът да изпълзи от дупката си, белким и у нас се запролети…
Междувременно на терена на голямата игра, поне привидно, такива въпроси отдавна са разрешени. Или съществуват в доста по-богата палитра от нюанси. (Което всъщност невинаги е за добро, но нейсе…) Да вземем например Алис Вайдел. „Как е възможно хомосексуална жена да е начело на „Алтернатива за Германия“?“ – пита Светла Енчева и дава няколко по-прости и няколко по-сложни отговора на въпроса. Да започнем с това, че нито АзГ е „Възраждане“, нито привържениците на партията, включително самата Алис Вайдел, са толкова отявлено анти-ЛГБТИ, колкото нашите крайнодесни патриоти и популисти. Именно това позволява сексуалната идентичност на Вайдел да бъде ловко инструментализирана, така че да легитимира АзГ като толерантна партия и заедно с това да подсили контура на заплахата, която мюсюлманските имигранти представляват за жените и хомосексуалните според наратива на крайнодесните. Ха сега де…
Връщаме се на родния черно-бял терен, където, както се разбрахме, нюансите са кът и ако искаш да разрешиш един проблем, най-лесно е просто да го забраниш. Така действаме и с наркотиците. Един ден забраняваме едно вещество, появява се друго, забраняваме и него, появява се трето – бам! – отстрелваме го. И така… до безкрайност като в тъпа аркадна игра. А работещата стратегия не се заключава в забрани и санкции, а в превенция, и то на много нива. Повече за борбата с наркотиците по принцип и в момента, по света и у нас четете в статията на Юлия Георгиева „Слонът в стаята, или защо употребата на наркотици се увеличава“.
И докато се сипят забрани отляво и отдясно, и докато МОН се занимава с религиозното обучение и централизираното дисциплиниране на децата в училище, седмицата удря дъното с новината за (само!) 8-годишното лишаване от свобода, присъдено на нечовешкия изрод Петър Чернев. Въпросният малтретирал 5-годишния си доведен син, вследствие на което детето – според данни от ТЕЛК – е загубило 60% от здравето си (вероятно се има предвид физическото; за психическото не става дума, не и в България!). Майката на детето – безучастна свидетелка на издевателствата – се разминава с парична глоба от 4000 лв. Държава, в която бебетата се хранят скришно, сакън да не нарушат общественото благоприличие, в която се въвежда оценка за дисциплина на децата, а малтретиращите ги възрастни едва ли не биват помилвани, заслужава всичко, което ѝ се случва и предстои да ѝ се случи.
Дърпаме завесата, за да влезе малко слънце, преди да сме се угнетили до смърт. За това ни помага Ина Иванова, която ни среща с „Димитър Панайотов и Александър Николов от „Ден“: С лице към фактите“. Документалистиката им е пример за отговорност и грижа към отделния човек и уж незначителните житейски подробности, за вчувстване в съдбите на другите, за неотстъпно вървене на страната на справедливостта – не абстрактната, а тази, която ни се разкрива във всекидневните избори и жестове.
Удължаваме удоволствието от срещите с „Тези хора“ чрез редовната ни рубрика за книжни срещи, които също няма да ни разочароват. Тази седмица в „По буквите“ Зорница Христова ни препоръчва новата дългоочаквана и „безспорна“ стихосбирка на Никола Петров и три пиеси на Тенеси Уилямс в превод на Евгения Панчева. И двете книги рязко ни издигат над „ниските топки“ на деня и ни напомнят, че четенето все още е един от малкото познати начини за оцеляване.
За нови начини на оцеляване и разумно съществуване става дума и в научните новини от Михаил Ангелов, където „Титанови сърца, генни редакции, биополимери и една космическа одисея с щастлив край“ обрисуват реалност, която точно в този исторически момент изглежда почти паралелна на обитаваната от нас. В нея обречените оцеляват, болните получават по-добра грижа, а Космосът е точка, в която духът (а не амбицията) укрепва и се извисява.
Стихотворението на месец март е от Рада Александрова. В него има и дъжд, и болка, и тържество, и една особена тъмна и природна радост, която изригва само напролет.
Ще възкръсне ли
тази земя.
Ще растат ли
треви и дървета.
Пита стихотворението. И ние питаме същото, борим се със страховете си и се опитваме да не губим надежда.
Оставяме ви да изпратите седмицата и месеца в компанията на любимата ни E.T., която – поради извънземното си естество – следи сигналите и прозира строго секретните връзки в реалността, включително телефонните между Веска, Стефка, Янка, Ванга и така до Нострадамус по права линия.
Ако и вие смятате, че е важно да не изгубим сигнала, може да ни подкрепите, лесно е – клик-клик, пиу-пиу. Айде готово.
Приятно четене!
Foundation Model for Personalized Recommendation
Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/foundation-model-for-personalized-recommendation-1a0bd8e02d39
By Ko-Jen Hsiao, Yesu Feng and Sudarshan Lamkhede
Motivation
Netflix’s personalized recommender system is a complex system, boasting a variety of specialized machine learned models each catering to distinct needs including “Continue Watching” and “Today’s Top Picks for You.” (Refer to our recent overview for more details). However, as we expanded our set of personalization algorithms to meet increasing business needs, maintenance of the recommender system became quite costly. Furthermore, it was difficult to transfer innovations from one model to another, given that most are independently trained despite using common data sources. This scenario underscored the need for a new recommender system architecture where member preference learning is centralized, enhancing accessibility and utility across different models.
Particularly, these models predominantly extract features from members’ recent interaction histories on the platform. Yet, many are confined to a brief temporal window due to constraints in serving latency or training costs. This limitation has inspired us to develop a foundation model for recommendation. This model aims to assimilate information both from members’ comprehensive interaction histories and our content at a very large scale. It facilitates the distribution of these learnings to other models, either through shared model weights for fine tuning or directly through embeddings.
The impetus for constructing a foundational recommendation model is based on the paradigm shift in natural language processing (NLP) to large language models (LLMs). In NLP, the trend is moving away from numerous small, specialized models towards a single, large language model that can perform a variety of tasks either directly or with minimal fine-tuning. Key insights from this shift include:
- A Data-Centric Approach: Shifting focus from model-centric strategies, which heavily rely on feature engineering, to a data-centric one. This approach prioritizes the accumulation of large-scale, high-quality data and, where feasible, aims for end-to-end learning.
- Leveraging Semi-Supervised Learning: The next-token prediction objective in LLMs has proven remarkably effective. It enables large-scale semi-supervised learning using unlabeled data while also equipping the model with a surprisingly deep understanding of world knowledge.
These insights have shaped the design of our foundation model, enabling a transition from maintaining numerous small, specialized models to building a scalable, efficient system. By scaling up semi-supervised training data and model parameters, we aim to develop a model that not only meets current needs but also adapts dynamically to evolving demands, ensuring sustainable innovation and resource efficiency.
Data
At Netflix, user engagement spans a wide spectrum, from casual browsing to committed movie watching. With over 300 million users at the end of 2024, this translates into hundreds of billions of interactions — an immense dataset comparable in scale to the token volume of large language models (LLMs). However, as in LLMs, the quality of data often outweighs its sheer volume. To harness this data effectively, we employ a process of interaction tokenization, ensuring meaningful events are identified and redundancies are minimized.
Tokenizing User Interactions: Not all raw user actions contribute equally to understanding preferences. Tokenization helps define what constitutes a meaningful “token” in a sequence. Drawing an analogy to Byte Pair Encoding (BPE) in NLP, we can think of tokenization as merging adjacent actions to form new, higher-level tokens. However, unlike language tokenization, creating these new tokens requires careful consideration of what information to retain. For instance, the total watch duration might need to be summed or engagement types aggregated to preserve critical details.

This tradeoff between granular data and sequence compression is akin to the balance in LLMs between vocabulary size and context window. In our case, the goal is to balance the length of interaction history against the level of detail retained in individual tokens. Overly lossy tokenization risks losing valuable signals, while too granular a sequence can exceed practical limits on processing time and memory.
Even with such strategies, interaction histories from active users can span thousands of events, exceeding the capacity of transformer models with standard self attention layers. In recommendation systems, context windows during inference are often limited to hundreds of events — not due to model capability but because these services typically require millisecond-level latency. This constraint is more stringent than what is typical in LLM applications, where longer inference times (seconds) are more tolerable.
To address this during training, we implement two key solutions:
- Sparse Attention Mechanisms: By leveraging sparse attention techniques such as low-rank compression, the model can extend its context window to several hundred events while maintaining computational efficiency. This enables it to process more extensive interaction histories and derive richer insights into long-term preferences.
- Sliding Window Sampling: During training, we sample overlapping windows of interactions from the full sequence. This ensures the model is exposed to different segments of the user’s history over multiple epochs, allowing it to learn from the entire sequence without requiring an impractically large context window.
At inference time, when multi-step decoding is needed, we can deploy KV caching to efficiently reuse past computations and maintain low latency.
These approaches collectively allow us to balance the need for detailed, long-term interaction modeling with the practical constraints of model training and inference, enhancing both the precision and scalability of our recommendation system.
Information in Each ‘Token’: While the first part of our tokenization process focuses on structuring sequences of interactions, the next critical step is defining the rich information contained within each token. Unlike LLMs, which typically rely on a single embedding space to represent input tokens, our interaction events are packed with heterogeneous details. These include attributes of the action itself (such as locale, time, duration, and device type) as well as information about the content (such as item ID and metadata like genre and release country). Most of these features, especially categorical ones, are directly embedded within the model, embracing an end-to-end learning approach. However, certain features require special attention. For example, timestamps need additional processing to capture both absolute and relative notions of time, with absolute time being particularly important for understanding time-sensitive behaviors.
To enhance prediction accuracy in sequential recommendation systems, we organize token features into two categories:
- Request-Time Features: These are features available at the moment of prediction, such as log-in time, device, or location.
- Post-Action Features: These are details available after an interaction has occurred, such as the specific show interacted with or the duration of the interaction.
To predict the next interaction, we combine request-time features from the current step with post-action features from the previous step. This blending of contextual and historical information ensures each token in the sequence carries a comprehensive representation, capturing both the immediate context and user behavior patterns over time.
Considerations for Model Objective and Architecture
As previously mentioned, our default approach employs the autoregressive next-token prediction objective, similar to GPT. This strategy effectively leverages the vast scale of unlabeled user interaction data. The adoption of this objective in recommendation systems has shown multiple successes [1–3]. However, given the distinct differences between language tasks and recommendation tasks, we have made several critical modifications to the objective.
Firstly, during the pretraining phase of typical LLMs, such as GPT, every target token is generally treated with equal weight. In contrast, in our model, not all user interactions are of equal importance. For instance, a 5-minute trailer play should not carry the same weight as a 2-hour full movie watch. A greater challenge arises when trying to align long-term user satisfaction with specific interactions and recommendations. To address this, we can adopt a multi-token prediction objective during training, where the model predicts the next n tokens at each step instead of a single token[4]. This approach encourages the model to capture longer-term dependencies and avoid myopic predictions focused solely on immediate next events.
Secondly, we can use multiple fields in our input data as auxiliary prediction objectives in addition to predicting the next item ID, which remains the primary target. For example, we can derive genres from the items in the original sequence and use this genre sequence as an auxiliary target. This approach serves several purposes: it acts as a regularizer to reduce overfitting on noisy item ID predictions, provides additional insights into user intentions or long-term genre preferences, and, when structured hierarchically, can improve the accuracy of predicting the target item ID. By first predicting auxiliary targets, such as genre or original language, the model effectively narrows down the candidate list, simplifying subsequent item ID prediction.
Unique Challenges for Recommendation FM
In addition to the infrastructure challenges posed by training bigger models with substantial amounts of user interaction data that are common when trying to build foundation models, there are several unique hurdles specific to recommendations to make them viable. One of unique challenges is entity cold-starting.
At Netflix, our mission is to entertain the world. New titles are added to the catalog frequently. Therefore the recommendation foundation models require a cold start capability, which means the models need to estimate members’ preferences for newly launched titles before anyone has engaged with them. To enable this, our foundation model training framework is built with the following two capabilities: Incremental training and being able to do inference with unseen entities.
- Incremental training : Foundation models are trained on extensive datasets, including every member’s history of plays and actions, making frequent retraining impractical. However, our catalog and member preferences continually evolve. Unlike large language models, which can be incrementally trained with stable token vocabularies, our recommendation models require new embeddings for new titles, necessitating expanded embedding layers and output components. To address this, we warm-start new models by reusing parameters from previous models and initializing new parameters for new titles. For example, new title embeddings can be initialized by adding slight random noise to existing average embeddings or by using a weighted combination of similar titles’ embeddings based on metadata. This approach allows new titles to start with relevant embeddings, facilitating faster fine-tuning. In practice, the initialization method becomes less critical when more member interaction data is used for fine-tuning.
- Dealing with unseen entities : Even with incremental training, it’s not always guaranteed to learn efficiently on new entities (ex: newly launched titles). It’s also possible that there will be some new entities that are not included/seen in the training data even if we fine-tune foundation models on a frequent basis. Therefore, it’s also important to let foundation models use metadata information of entities and inputs, not just member interaction data. Thus, our foundation model combines both learnable item id embeddings and learnable embeddings from metadata. The following diagram demonstrates this idea.

To create the final title embedding, we combine this metadata-based embedding with a fully-learnable ID-based embedding using a mixing layer. Instead of simply summing these embeddings, we use an attention mechanism based on the “age” of the entity. This approach allows new titles with limited interaction data to rely more on metadata, while established titles can depend more on ID-based embeddings. Since titles with similar metadata can have different user engagement, their embeddings should reflect these differences. Introducing some randomness during training encourages the model to learn from metadata rather than relying solely on ID embeddings. This method ensures that newly-launched or pre-launch titles have reasonable embeddings even with no user interaction data.
Downstream Applications and Challenges
Our recommendation foundation model is designed to understand long-term member preferences and can be utilized in various ways by downstream applications:
- Direct Use as a Predictive Model The model is primarily trained to predict the next entity a user will interact with. It includes multiple predictor heads for different tasks, such as forecasting member preferences for various genres. These can be directly applied to meet diverse business needs..
- Utilizing embeddings The model generates valuable embeddings for members and entities like videos, games, and genres. These embeddings are calculated in batch jobs and stored for use in both offline and online applications. They can serve as features in other models or be used for candidate generation, such as retrieving appealing titles for a user. High-quality title embeddings also support title-to-title recommendations. However, one important consideration is that the embedding space has arbitrary, uninterpretable dimensions and is incompatible across different model training runs. This poses challenges for downstream consumers, who must adapt to each retraining and redeployment, risking bugs due to invalidated assumptions about the embedding structure. To address this, we apply an orthogonal low-rank transformation to stabilize the user/item embedding space, ensuring consistent meaning of embedding dimensions, even as the base foundation model is retrained and redeployed.
- Fine-Tuning with Specific Data The model’s adaptability allows for fine-tuning with application-specific data. Users can integrate the full model or subgraphs into their own models, fine-tuning them with less data and computational power. This approach achieves performance comparable to previous models, despite the initial foundation model requiring significant resources.
Scaling Foundation Models for Netflix Recommendations
In scaling up our foundation model for Netflix recommendations, we draw inspiration from the success of large language models (LLMs). Just as LLMs have demonstrated the power of scaling in improving performance, we find that scaling is crucial for enhancing generative recommendation tasks. Successful scaling demands robust evaluation, efficient training algorithms, and substantial computing resources. Evaluation must effectively differentiate model performance and identify areas for improvement. Scaling involves data, model, and context scaling, incorporating user engagement, external reviews, multimedia assets, and high-quality embeddings. Our experiments confirm that the scaling law also applies to our foundation model, with consistent improvements observed as we increase data and model size.

Conclusion
In conclusion, our Foundation Model for Personalized Recommendation represents a significant step towards creating a unified, data-centric system that leverages large-scale data to increase the quality of recommendations for our members. This approach borrows insights from Large Language Models (LLMs), particularly the principles of semi-supervised learning and end-to-end training, aiming to harness the vast scale of unlabeled user interaction data. Addressing unique challenges, like cold start and presentation bias, the model also acknowledges the distinct differences between language tasks and recommendation. The Foundation Model allows various downstream applications, from direct use as a predictive model to generate user and entity embeddings for other applications, and can be fine-tuned for specific canvases. We see promising results from downstream integrations. This move from multiple specialized models to a more comprehensive system marks an exciting development in the field of personalized recommendation systems.
Acknowledgements
Contributors to this work (name in alphabetical order): Ai-Lei Sun Aish Fenton Anne Cocos Anuj Shah Arash Aghevli Baolin Li Bowei Yan Dan Zheng Dawen Liang Ding Tong Divya Gadde Emma Kong Gary Yeh Inbar Naor Jin Wang Justin Basilico Kabir Nagrecha Kevin Zielnicki Linas Baltrunas Lingyi Liu Luke Wang Matan Appelbaum Michael Tu Moumita Bhattacharya Pablo Delgado Qiuling Xu Rakesh Komuravelli Raveesh Bhalla Rob Story Roger Menezes Sejoon Oh Shahrzad Naseri Swanand Joshi Trung Nguyen Vito Ostuni Wei Wang Zhe Zhang
Reference
- C. K. Kang and J. McAuley, “Self-Attentive Sequential Recommendation,” 2018 IEEE International Conference on Data Mining (ICDM), Singapore, 2018, pp. 197–206, doi: 10.1109/ICDM.2018.00035.
- F. Sun et al., “BERT4Rec: Sequential Recommendation with Bidirectional Encoder Representations from Transformer,” Proceedings of the 28th ACM International Conference on Information and Knowledge Management (CIKM ‘19), Beijing, China, 2019, pp. 1441–1450, doi: 10.1145/3357384.3357895.
- J. Zhai et al., “Actions Speak Louder than Words: Trillion-Parameter Sequential Transducers for Generative Recommendations,” arXiv preprint arXiv:2402.17152, 2024.
- F. Gloeckle, B. Youbi Idrissi, B. Rozière, D. Lopez-Paz, and G. Synnaeve, “Better & Faster Large Language Models via Multi-token Prediction,” arXiv preprint arXiv:2404.19737, Apr. 2024.

Foundation Model for Personalized Recommendation was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.