Linux offers two broad ways of performing I/O to files. Buffered I/O,
which is the usual way of accessing a file, stores a copy of the
transferred data in the kernel’s page cache to speed future accesses.
Direct I/O, instead, moves data directly between the storage device and a
user-space buffer, avoiding the page cache. Both modes have their
advantages and disadvantages. In 2019, Jens Axboe proposed an uncached buffered mode to get some
of the advantages of both, but that effort stalled at the time. Now, uncached buffered
I/O is back with some impressive performance results behind it.
Beginning in early October, Rapid7 has observed a resurgence of activity related to the ongoing social engineering campaign being conducted by Black Basta ransomware operators. Rapid7 initially reported the discovery of the novel social engineering campaign back in May, 2024, followed by an update in August 2024, when the operators updated their tactics and malware payloads and began sending lures via Microsoft Teams. Now, the procedures followed by the threat actors in the early stages of the social engineering attacks have been refined again, with new malware payloads, improved delivery, and increased defense evasion.
Overview
The social engineering attacks are still initiated in a similar manner. Users within the target environment will be email bombed by the threat actor, which is often achieved by signing up the user’s email to numerous mailing lists simultaneously. After the email bomb, the threat actor will reach out to the impacted users. Rapid7 has observed the initial contact still occurs primarily through usage of Microsoft Teams, by which the threat actor, as an external user, will attempt to call or message the impacted user to offer assistance. The account domains in use include both Azure/Entra tenant subdomains (e.g., username[@]tenantsubdomain[.]onmicrosoft[.]com) and custom domains (e.g., username[@]cofincafe[.]com).
In many cases, Rapid7 has observed that the threat actor will pretend to be a member of the target organization’s help desk, support team, or otherwise present themself as IT staff. Below are examples of Microsoft Teams display names observed, by Rapid7, to be in use by operators. The display names may or may not be padded with whitespace characters. Rapid7 has also observed threat actors use a first and last name, as the chat display name and/or account username, to impersonate an IT staff member within the targeted organization.
Operator Chat Display Name
Help Desk
HELP DESK
Help Desk Manager
Technical Support
Administracion
If the user interacts with the lure, either by answering the call or messaging back, the threat actor will attempt to get the user to install or execute a remote management (RMM) tool, including, but not limited to, QuickAssist, AnyDesk, TeamViewer, Level, or ScreenConnect. Rapid7 has also observed attempts to leverage the OpenSSH client, a native Windows utility, to establish a reverse shell. In at least one instance, the threat actor shared a QR code with the targeted user. The purpose of the QR code is unconfirmed but appears to be an attempt to bypass MFA after stealing a user’s credentials. The URL embedded within the QR code adheres to the following format: hxxps://<company_name>[.]qr-<letter><number>[.]com.
Figure 1. A QR code (obfuscation by Rapid7) sent by an operator.
In a majority of cases, Rapid7 has observed that the operator, after gaining access to the user’s asset via RMM tool, will then attempt to download and execute additional malware payloads. In one case handled by Rapid7, the operator requested more time — potentially to hand off the access to another member of the group.
Figure 2. An operator stalls for time.
The payload delivery methods vary per case, but have included external compromised SharePoint instances, common file sharing websites, servers rented through hosting providers, or even direct upload to the compromised asset in the case of RMM tool remote control. In one case, the operator used the group’s custom credential harvester to dump the user’s credentials, the results for which were subsequently uploaded to a file sharing site — publicly exposing the stolen credentials. SharePoint has been used to distribute copies of AnyDesk portable, likely to circumvent security measures that would prevent the user from downloading it directly from anydesk[.]com. Such attempts have been blocked by web proxy in previous cases.
The overall goal following initial access appears to be the same: to quickly enumerate the environment and dump the user’s credentials. When possible, operators will also still attempt to steal any available VPN configuration files. With the user’s credentials, organization VPN information, and potential MFA bypass, it may be possible for them to authenticate directly to the target environment.
Rapid7 has observed usage of the same credential harvesting executable, previously reported as AntiSpam.exe, though it is now delivered in the form of a DLL and most commonly executed via rundll32.exe. Whereas before it was an unobfuscated .NET executable, the program is now commonly contained within a compiled 64-bit DLL loader. Rapid7 has analyzed at least one sample that has also been obfuscated using the group’s custom packer. The newest versions of the credential harvester now save output to the file 123.txt in the user’s %TEMP% directory, an update from the previous qwertyuio.txt file, though versions of the DLL distributed earlier in the campaign would still output to the previous file.
Figure 3. The credential harvesting prompt shown to the user upon executing the DLL (redaction by Rapid7).
The credential harvester is most commonly followed by the execution of a loader such as Zbot (a.k.a. Zloader) or DarkGate. This can then serve as a gateway to the execution of subsequent payloads in memory, facilitate data theft, or otherwise perform malicious actions. Rapid7 has also observed operators distributing alternate payload archives containing Cobalt Strike beacon loaders and a pair of Java payloads containing a user credential harvester variant and a custom multi-threaded beacon by which to remotely execute PowerShell commands. In some cases, operators have sent the user a short command, via Teams, which will then begin an infection chain after execution by the targeted user.
Rapid7 continues to observe inconsistent usage of the group’s custom packer to deliver various malware payloads, including their custom credential harvester. A YARA rule is now publicly available that can be used to detect the packer. For example, this packer was used to deliver several obfuscated versions of Black Basta ransomware, obtained via open source intelligence, which directly links operators to the ongoing social engineering campaign.
At the time of writing, the threat actors behind the campaign continue to update both their strategy for gaining initial access and the tools subsequently used. For example, around the time the most recent campaign activity began, Rapid7 observed the delivery of a timestamped and versioned payload archive, 171024_V1US.zip (2024-10-17, version 1, US), which, when compared to a more recently delivered archive, 171124_V15.zip (2024-11-17, version 15), highlights the rapid iteration being undertaken. Many of the payloads being delivered follow a similar pattern as previous activity and often consist of a legitimate file where an export or function entry point has been overwritten to jump to malicious code, and the result is signed with a likely stolen code signing certificate.
Intrusions related to the campaign should be taken seriously — the intent goes beyond typical phishing activity. Past campaign activity has led to the deployment of Black Basta ransomware. While Rapid7 has handled a high volume of incidents related to the current social engineering campaign across a variety of customer environments, to date, every case has been contained before the operator was able to move laterally beyond the targeted user’s asset.
Technical Analysis
Initial Access
Each attack is preceded by the targeted user receiving an often overwhelming amount of emails. An operator will then attempt to contact the user via Microsoft Teams, either via messaging or calling, by which they will pretend to offer assistance. Operators will attempt to impersonate the organization’s help desk, such as using the names of existing staff members.
During this social engineering stage, operators often need to troubleshoot with the user to establish remote control of the user’s asset. Based on the environment, for example, RMM tool downloads or execution may be blocked (often some, but not all) or QuickAssist may be disabled, causing the operator to cycle through their options at establishing a foothold. One of the most common first steps after gaining either the confidence of the user, or remote access, is to execute a custom credential harvester.
Credential Harvesting
The credential harvester used by operators, for example SafeStore.dll (SHA256: 3B7E06F1CCAA207DC331AFD6F91E284FEC4B826C3C427DFFD0432FDC48D55176), is an updated version of the previously analyzed program AntiSpam.exe. The DLL variant of the credential harvester is executed by a command like the following example:
rundll32.exe SafeStore.dll,epaas_request_clone
The module will quickly execute three enumeration commands to gather system information — systeminfo, route print, ipconfig /all — and then prompt the user for their password. The user’s credentials are appended onto a new line of the text file 123.txt with each attempt, after the enumeration command output, regardless of whether the credentials are correct. If the user enters the wrong password, they will be prompted to try again. The output for the enumeration commands and the user’s credentials were saved to the file qwertyuio.txt in older versions of the harvester, but are now saved to 123.txt, within the user’s %TEMP% directory. The enumeration commands within the updated version are executed via successive calls to CreateProcessA.
Figure 4. Success and failure messages for the credential harvester.
Based on analysis of one credential harvester sample, EventCloud.dll, the program was present in shellcode form. The shellcode is decrypted from the Cursor Group 880 resource embedded within the executable, using the XOR key 5A 3C 77 6E 33 30 4D 38 4F 38 40 78 41 58 51 30 42 5F 3F 67 71 00, and then injected locally. The following strings which were extracted from the shellcode show the output file and list dynamically loaded libraries:
Credential Harvester Strings
–
–
–
–
cmd.exe /c
%s%s
%s%s%s%s
123.txt
ooki
Update
filter kb_outl
Need credentials to update…
Username:
Password:
ntdll.dll
Gdi32.dll
user32.dll
msvcrt.dll
ucrtbase.dll
Comctl32.dll
Advapi32.dll
kernel32.dll
–
–
The Java variant of the credential harvester, identity.jar, provides a similar prompt to the user, though when a password is entered it is appended, without the username, to a .txt file with a random 10-letter alphabetic name to the current working directory. The cancel button on the prompt, shown below, is not functional and the prompt is drawn on top of other windows, meaning that it will not close until the user has entered their password correctly.
Figure 5. The credential harvesting prompt created by `identity.jar`.
Malware Payloads
Following execution of a credential harvester, an operator will typically infect the asset with Zbot or DarkGate. One of the Zbot samples delivered after initial access, SyncSuite.exe (SHA256: DB34E255AA4D9F4E54461571469B9DD53E49FEED3D238B6CFB49082DE0AFB1E4) contains similar functionality and strings to other Zbot/Zloader samples previously reported by ZScaler. However, in addition to previously observed strings, the sample also contains encrypted strings for an embedded command help menu, error messages, and more. Rapid7 observed the embedded malware version was 2.9.4.0.
Upon execution, the malware will copy itself to a random folder within the %APPDATA% directory. If the file does not have its original filename however, the process will immediately exit. The malware also contains the functionality to establish persistence either via a Run key at HKCU\Software\Microsoft\Windows\CurrentVersion\Run or a scheduled task named after the executable, which executes the malware copy in %APPDATA% whenever the user logs on. After collecting the hostname, username, and the installation date from the InstallDate value contained within the registry key HKLM\Software\Microsoft\Windows NT\CurrentVersion, this data is concatenated (delimited by underscore characters) and encrypted, along with other config information. It is then stored within the user’s registry inside a random key created at HKCU\Software\Microsoft\. The analyzed sample will also load a fresh copy of ntdll.dll to avoid hooking, which is then used to perform calls to NTAPI functions. SyncSuite.exe ultimately injects itself into a suspended instance of msedge.exe, created using NtCreateUserProcess and executed via ResumeThread, a technique known as Process Hollowing.
All of the strings used by the malware are stored encrypted within the .rdata section along with the configuration. The strings are decrypted using an obfuscated loop that is ultimately a simple XOR operation with the hard coded key 16 EB D5 3E AA E6 51 09 14 D3 DF 18 AD D6 1B BD BE, which is also stored in the .rdata section. The configuration is decrypted using an RC4 key, F3 F9 F7 FB FA F3 F7 F7 FF F5 F2 F3 FA FD FE F2 for this sample. The decrypted configuration for SyncSuite.exe can be seen below, with empty rows removed. The configuration contains a different public RSA key and botnet ID than the one previously shared by ThreatLabz, indicating that the campaign is being run by a different affiliate. All decrypted strings from SyncSuite.exe can be seen in the Zbot Strings section following other Indicators of Compromise.
Figure 6. The decrypted Zbot configuration for `SyncSuite.exe` (1264 bytes).
Rapid7 has also observed the delivery of DarkGate malware following initial access. One payload archive contained both a DarkGate infection initiation script, test.vbs, and an executable copy of the DarkGate malware itself, SafeFilter.exe (SHA256: EF28A572CDA7319047FBC918D60F71C124A038CD18A02000C7AB413677C5C161 ), though this copy is packed using the group’s custom packer. The final payload containing the DarkGate malware, after several layers of decrypting and loading, contains the version string 7.0.6. If the folder c:\debugg exists on the system when the malware is executed it will display the version number via MessageBoxA. The configuration for this sample can be seen below along with hard coded commands. Notably, the campaign ID for the sample appears to be drk2.
Figure 7. DarkGate displays its version using a debug message box.
The configuration is decrypted with the key ckcilIcconnh within a customized XOR loop near the beginning of execution to reveal CRLF delimited options. However, due to the implementation of the decryption loop, the keyspace is effectively reduced to that of a single byte (0-255), after the first byte. This makes the XOR key for the majority of the config 0x60, for this sample allowing for the encrypted data to be trivially bruteforced.
| SafeFilter.exe DarkGate Config |-|
Key-Value Pair
Description
0=179.60.149[.]194|
C2 domains or IP addresses, delimited with ‘|’ characters
8=No
If enabled and the file C:\ProgramData\hedfdfd\Autoit3.exe does not exist, call MessageBoxTimeoutA using keys 11 and 12 and a timeout of 1770ms.
11=Error
Used by key 8 as a message box title.
12=PyKtS5Q
The string Error, base64 encoded with the custom alphabet zLAxuU0kQKf3sWE7ePRO2imyg9GSpVoYC6rhlX48ZHnvjJDBNFtMd1I5acwbqT+=. Used by key 8 as a message box caption.
13=6
Unknown
14=Yes
Unknown
15=80
C2 communication port.
1=Yes
Enables infection.
32=Yes
If enabled, attempt bypass of detected security products. For example, enables calls to RtlAdjustPrivilege and NtRaiseHardError to cause a crash if hdkcgae is not present in C:\temp\ and a Kaspersky product has been detected.
3=No
If disabled, do an anti-vm display check.
4=No
If enabled, compare system drive size to key 18. If below, exit.
18=100
Minimum drive size in GB.
6=No
If enabled and key 3 is disabled, check the display for known virtual machine display strings using EnumDisplayDevicesA. If matched, exit. Failed to match properly when tested.
7=No
If enabled, compare system RAM to key 19. If below, exit.
19=4096
Minimum RAM size in MB.
5=No
If enabled, check the registry key ProcessorNameString at HKLM\HARDWARE\DESCRIPTION\System\CentralProcessor\0 for xeon. If found, exit.
21=No
Unknown
22
Not present in the config for this sample, but is still checked for in the code. If enabled, set the variant string to DLL, otherwise ?.
23=Yes
If enabled, set the variant string to AU3 for Autoit3 payloads.
31=No
If enabled, set the variant string to AHK for AutoHotKey payloads.
25=drk2
Campaign ID
26=No
Unknown
27=rsFxMyDX
Decryption key, also used to bound/find payloads stored within other files.
/c cd /d "C:\Users\User\AppData\Roaming<browser_dir>" && move <browser_name> <browser_name><random_alphabet_string>
/c cd /d "C:\Users\User\AppData\Local" && move <browser_name> <browser_name><random_alphabet_string>
/c cmdkey /delete:
/c cmdkey /list > c:\temp\cred.txt
/c del /q /f /s C:\Users\User\AppData\Roaming\Mozilla\firefox*
/c ping 127.0.0.1 & del /q /f /s c:\temp & del /q /f /s C:\ProgramData\hedfdfd\ & rmdir /s /q C:\ProgramData\hedfdfd\
/c shutdown -f -r -t 0
/c shutdown -f -s -t 0
/c wmic ComputerSystem get domain > C:\ProgramData\hedfdfd\fcadaab
During execution, DarkGate will hash certain strings and use the result to create or check files at the directories C:\ProgramData\hedfdfd(mainfolder) and C:\temp\. The hashing algorithm uses a randomized key generated at runtime, so the hashes across infections will be different. Commonly used strings and their resultant hash, for the analysis environment, are shown below.
Path String
DarkGate Custom Hash
mainfolder
hedfdfd
logsfolder
fhhcfhh
settings
dhkbbfc
domain
fcadaab
mutex0
hfgdced
mutex1
cekchde
au3
dgfeabe
c.txt
adfcbdd
cc.txt
dehgaba
script
daaadeh
fs.txt
hdkcgae
DarkGate may also change its behavior if a known security product is detected. This is achieved by using CreateToolhelp32Snapshot and related functions to loop through running processes which are compared to a hard-coded list. The malware will also check for known installation directories using GetFileAttributesA. If a security product is found, a flag will be set which may alter the execution path. Only the following products had associated flags:
DarkGate “Supported” Security Products
–
–
–
–
Windows Defender
Sophos
Quick Heal
MalwareBytes
Panda Security
Norton/Symantec
ESET/Nod32
Kaspersky
Avast
SentinelOne
Bitdefender
–
–
–
–
At the end of the first execution of the DarkGate payload, it will then attempt to inject itself into a host process. First, DarkGate will select the injection target by searching a list of hard coded directories for any executable that contains the string updatecore.exe, subdirectories included. The path C:\Program Files (x86)\Microsoft\EdgeUpdate\ is searched first, with the fallback being C:\Program Files (x86)\Microsoft\EdgeUpdate\MicrosoftEdgeUpdate.exe. If a matching Edge executable is not found, the path C:\Program Files (x86)\Google\Update\ is then searched. If that also fails, the malware will attempt to use C:\Windows\Microsoft.NET\Framework\v4.0.30319\msbuild.exe.
After successfully choosing the injection target, DarkGate will then inject itself into the target process using shellcode, terminating the original instance of the final DarkGate payload after executing the shellcode. When creating an instance of the target process to inject, DarkGate will also attempt to spoof the parent process ID (PPID) of the injection target by enumerating running processes for accessibility using OpenProcess and then randomly selecting one from an assembled list. The PPID of the target is then updated using UpdateProcThreadAttribute prior to creation with CreateProcessA.
Execution of the injected process is coordinated by checking for the presence of two file based mutexes within C:\ProgramData\hedfdfd\ (mainfolder). Each instance of the DarkGate malware checks both of the file-based mutexes. The file mutex usage is checked via calls to CreateFileA using an exclusive share mode flag (0) and a creation disposition of CREATE_ALWAYS, which means that if the mutex is already in usage by another DarkGate instance the call will fail. If the call to both mutexes created by DarkGate, hfgdced and cekchde, fails, DarkGate will exit. As a result of having two mutexes, DarkGate will typically run within two injected process instances at the same time, so if one process is terminated, the remaining instance will spawn another. If a DarkGate instance is spawned and both calls to open the file based mutexes fail, indicating two existing DarkGate instances, the new instance will terminate. This technique is rarely used by malware developers and highlights the sophistication of DarkGate malware.
DarkGate will unconditionally log keystrokes as well as clipboard data that is under 1024 bytes. The logged data is stored encrypted at C:\ProgramData\hedfdfd\fhhcfhh (mainfolder\logsfolder) within files named <date>.log. The logged data may be sent directly to the C2 address contained within the config. A thread is also created to persist on infected systems by creating the Run key daaadeh (script) at HKCU\Software\Microsoft\Windows\CurrentVersion\Run. The Run key will point to the copies of Autoit3.exe and the compiled AU3 script payload dgfeabe.a3x (au3) created at C:\ProgramData\hedfdfd (mainfolder), with the former executing the latter every time the user logs on. When the AU3 script is executed, DarkGate reinfects the system. The thread continuously monitors the text within the infected user’s active window however, sleeping 1500ms between checks, and will delete the registry key if a blacklisted application is detected. This list includes popular analysis tools such as Process Hacker, Process Monitor, Task Manager, and even the Windows Registry Editor.
The DarkGate sample executed by SafeFilter.exe contains 78 remote commands, some of which can be seen below with their intended function. Every loop, the malware will re-send the text of the active window, user idle time, and whether or not the malware instance has admin rights, before checking for a command.
Command ID
Function
1000
Sleep for a randomized amount of time.
1004
Use MessageBoxA to display the message test msg.
1044,1045,1046
Click the user’s mouse at specified screen coordinates using SetCursorPos and successive calls to mouse_event. 1044 for double left-click. 1045 for single left click. 1046 for single right click.
1049
Create a remote shell via powershell.exe.
1059
Terminate process by PID.
1061
Inject DarkGate shellcode into a specified process or an Edge/Chrome process if none is selected. The shellcode is then executed via ResumeThread.
1062,1063,1064
Inject DarkGate shellcode into a specified process or cmd.exe if none is selected. The shellcode is then executed via CreateRemoteThread.
1066
Remove infection files by using cmd.exe to delete the staging directories C:\ProgramData\hedfdfd and c:\temp\.
1071
Steal sitemanager.xml and recentservers.xml from %APPDATA%\FileZilla\ if present.
1079
If admin, delete stored credentials found using cmdkey.
1080
Rename browser directories for Firefox, Chrome, and Brave if present after terminating the related browser executable. Attempt to steal Opera cookies if present, after terminating the process.
1081
Use NTAPI calls RtlAdjustPrivilege and NtRaiseHardError to crash the system.
1083
Use the shutdown command to turn the system off.
1084
Use the shutdown command to restart the system.
1089
If 1=Yes in config, reinfect system with AU3 payloads.
1093
Create a remote shell via cmd.exe.
1097
Infect system with AU3 variant. Creates the files script.a3x and Autoit3.exe in c:\temp and then executes script.a3x via Autoit3.exe using CreateProcessA.
1104
Infect system with AHK variant. Creates the files script.ahk, test.txt, and AutoHotkey.exe in c:\temp and then executes script.ahk via AutoHotkey.exe using CreateProcessA.
1108
Infect system with DLL variant. Creates the files libcurl.dll, test.txt, and GUP.exe in c:\temp and then executes GUP.exe via CreateProcessA.
1111
Create the files ransom.txt and decrypter.exe in c:\temp. Terminate decrypter.exe if already running and then execute decrypter.exe using CreateProcessA. Likely ransomware deployment method.
DarkGate Remote Command Related Strings
–
–
–
–
U_Binder
U_BotUpdate
U_Constantes
U_FTPRecovery
U_FileManager
U_FileManagerMisc
U_GetScreens
U_HVNC
U_HVNC_7
U_HWID
U_InfoRecovery
U_InjectOnFly
U_Keylogger
U_LNKStartup
U_MemExecute
U_MemExecuteMisc
U_RemoteScreen
U_SysApi
U_SysNtReadWrite
U_miniclipboard
u_AntiAntiStartup
u_Antis
u_AudioRecord
u_CustomBase64
u_ExtraMisc
u_HollowInstall
u_InjectEP
u_InvokeBSOD
u_RDPRecovery
u_Ransomware
u_ReadCookies
u_ReverseShell
u_RootkitMutex
u_Settings
u_SettingsPad
u_ShellcodeEP
u_UnlockCookies
u_loadpe
hxxps://ipinfo[.]io/ip
Mitigation Guidance
Rapid7 recommends taking the following precautions to limit exposure to these types of attacks:
Restrict the ability for external users to contact users via Microsoft Teams to the greatest extent possible. This can be done for example by blocking all external domains or creating a white/black list. Microsoft Teams will allow all external requests by default. For more information, see this reference.
Standardize remote management tools within the environment. For unapproved tools, block known hashes and domains to prevent usage. Hash blocking can be done, for example, via Windows AppLocker or an endpoint protection solution.
Provide user awareness training regarding the social engineering campaign. Familiarize users with official help desk and support procedures to enable them to spot and report suspicious requests.
Standardize VPN access. Traffic from known low cost VPN solutions should be blocked at a firewall level if there is no business use case.
Rapid7 Customers
InsightIDR, Managed Detection and Response, and Managed Threat Complete customers have existing detection coverage through Rapid7’s expansive library of detection rules. Rapid7 recommends installing the Insight agent on all applicable hosts to ensure visibility into suspicious processes and proper detection coverage. Below is a non-exhaustive list of detections that are deployed and will alert on behavior related to this activity:
Detections
Suspicious Chat Request – Potential Social Engineering Attempt
Initial Access – Potential Social Engineering Session Initiated Following Chat Request
Suspicious Conversation – Potential Social Engineering Message Interaction
Attacker Technique – Process Executed Using Nt Object Path
Suspicious Process – Enumeration Burst via ShellExecute
Version
6.0.0 of the Hurl command-line tool has been released. Hurl is
curl-powered utility that runs HTTP requests and tests defined in a
plain-text Hurl
file. Notable features in this release include the ability to
generate dynamic values with functions, shorter syntax, and an option
to export Hurl files to a list of curl commands. See the release
notes for a full list of changes and downloads.
Artificial intelligence (AI) is transforming industries, and education is no exception. AI-driven development environments (AIDEs), like GitHub Copilot, are opening up new possibilities, and educators and researchers are keen to understand how these tools impact students learning to code.
In our 50th research seminar, Nicholas Gardella, a PhD candidate at the University of Virginia, shared insights from his research on the effects of AIDEs on beginner programmers’ skills.
Nicholas Gardella focuses his research on understanding human interactions with artificial intelligence-based code generators to inform responsible adoption in computer science education.
Measuring AI’s impact on students
AI tools are becoming a big part of software development, but what does that mean for students learning to code? As tools like GitHub Copilot become more common, it’s crucial to ask: Do these tools help students to learn better and work more effectively, especially when time is tight?
This is precisely what Nicholas’s research aims to identify by examining the impact of AIDEs on four key areas:
Performance (how well students completed the tasks)
Workload (the effort required)
Emotion (their emotional state during the task)
Self-efficacy (their belief in their own abilities to succeed)
Nicholas conducted his study with 17 undergraduate students from an introductory computer science course, who were mostly first-time programmers, with different genders and backgrounds.
By luckybusiness
The students completed programming tasks both with and without the assistance of GitHub Copilot. Nicholas selected the tasks from OpenAI’s human evaluation data set, ensuring they represented a range of difficulty levels. He also used a repeated measures design for the study, meaning that each student had the opportunity to program both independently and with AI assistance multiple times. This design helped him to compare individual progress and attitudes towards using AI in programming.
Less workload, more performance and self-efficacy in learning
The results were promising for those advocating AI’s role in education. Nicholas’s research found that participants who used GitHub Copilot performed better overall, completing tasks with less mental workload and effort compared to solo programming.
Nicholas used several measures to find out whether AIDEs affected students’ emotional states.
However, the immediate impact on students’ emotional state and self-confidence was less pronounced. Initially, participants did not report feeling more confident while coding with AI. Over time, though, as they became more familiar with the tool, their confidence in their abilities improved slightly. This indicates that students need time and practice to fully integrate AI into their learning process. Students increasingly attributed their progress not to the AI doing the work for them, but to their own growing proficiency in using the tool effectively. This suggests that with sustained practice, students can gain confidence in their abilities to work with AI, rather than becoming overly reliant on it.
Students who used AI tools seemed to improve more quickly than students who worked on the exercises themselves.
A particularly important takeaway from the talk was the reduction in workload when using AI tools. Novice programmers, who often find programming challenging, reported that AI assistance lightened the workload. This reduced effort could create a more relaxed learning environment, where students feel less overwhelmed and more capable of tackling challenging tasks.
However, while workload decreased, use of the AI tool did not significantly boost emotional satisfaction or happiness during the coding process. Nicholas explained that although students worked more efficiently, using the AI tool did not necessarily make coding a more enjoyable experience. This highlights a key challenge for educators: finding ways to make learning both effective and engaging, even when using advanced tools like AI.
AI as a tool for collaboration, not replacement
Nicholas’s findings raise interesting questions about how AI should be introduced in computer science education. While tools like GitHub Copilot can enhance performance, they should not be seen as shortcuts for learning. Students still need guidance in how to use these tools responsibly. Importantly, the study showed that students did not take credit for the AI tool’s work — instead, they felt responsible for their own progress, especially as they improved their interactions with the tool over time.
Rick Payne and team / Better Images of AI / Ai is… Banner / CC-BY 4.0
Students might become better programmers when they learn how to work alongside AI systems, using them to enhance their problem-solving skills rather than relying on them for answers. This suggests that educators should focus on teaching students how to collaborate with AI, rather than fearing that these tools will undermine the learning process.
Bridging research and classroom realities
Moreover, the study touched on an important point about the limits of its findings. Since the experiment was conducted in a controlled environment with only 17 participants, researchers need to conduct further studies to explore how AI tools perform in real-world classroom settings. For example, the role of internet usage plays a fundamental role. It will be relevant to understand how factors such as class size, prior varying experience, and the age of students affect their ability to integrate AI into their learning.
In the follow-up discussion, Nicholas also demonstrated how AI tools are becoming more accessible within browsers and how teachers can integrate AI-driven development environments more easily into their courses. By making AI technology more readily available, these tools are democratising access to advanced programming aids, enabling students to build applications directly in their web browsers with minimal setup.
The path ahead
Nicholas’s talk provided an insightful look into the evolving relationship between AI tools and novice programmers. While AI can improve performance and reduce workload, it is not a magic solution to all the challenges of learning to code.
Based on the discussion after the talk, educators should support students in developing the skills to use these tools effectively, shaping an environment where they can feel confident working with AI systems. The researchers and educators agreed that more research is needed to expand on these findings, particularly in more diverse and larger-scale educational settings.
As AI continues to shape the future of programming education, the role of educators will remain crucial in guiding students towards responsible and effective use of these technologies, as we are only at the beginning.
Join our next seminar
In our current seminar series, we are exploring how to teach programming with and without AI technology. Join us at our next seminar on Tuesday, 10 December at 17:00–18:30 GMT to hear Leo Porter (UC San Diego) and Daniel Zingaro (University of Toronto) discuss how they are working to create an introductory programming course for majors and non-majors that fully incorporates generative AI into the learning goals of the course.
To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.
Security updates have been issued by Red Hat (go-toolset:rhel8, grafana, kernel, kernel-rt, kernel:4.18.0, pam, pam:1.5.1, pcs, postgresql:12, postgresql:15, postgresql:16, python3:3.6.8, qemu-kvm, rhc, rhc-worker-playbook, and virt:rhel and virt-devel:rhel) and SUSE (ansible-10, ansible-core, avahi, bpftool, python, python3, python36, webkit2gtk3, and xen).
It’s been the biggest year for elections in human history: 2024 is a “super-cycle” year in which 3.7 billion eligible voters in 72 countries had the chance to go the polls. These are also the first AI elections, where many feared that deepfakes and artificial intelligence-generated misinformation would overwhelm the democratic processes. As 2024 draws to a close, it’s instructive to take stock of how democracy did.
In a Pew survey of Americans from earlier this fall, nearly eight times as many respondents expected AI to be used for mostly bad purposes in the 2024 election as those who thought it would be used mostly for good. There are real concerns and risks in using AI in electoral politics, but it definitely has not been all bad.
The dreaded “death of truth” has not materialized—at least, not due to AI. And candidates are eagerly adopting AI in many places where it can be constructive, if used responsibly. But because this all happens inside a campaign, and largely in secret, the public often doesn’t see all the details.
Connecting with voters
One of the most impressive and beneficial uses of AI is language translation, and campaigns have started using it widely. Local governments in Japan and California and prominent politicians, including India Prime Minister Narenda Modi and New York City Mayor Eric Adams, used AI to translate meetings and speeches to their diverse constituents.
Even when politicians themselves aren’t speaking through AI, their constituents might be using it to listen to them. Google rolled out free translation services for an additional 110 languages this summer, available to billions of people in real time through their smartphones.
Other candidates used AI’s conversational capabilities to connect with voters. U.S. politicians Asa Hutchinson, Dean Phillips and Francis Suarez deployed chatbots of themselves in their presidential primary campaigns. The fringe candidate Jason Palmer beat Joe Biden in the American Samoan primary, at least partly thanks to using AI-generated emails, texts, audio and video. Pakistan’s former prime minister, Imran Khan, used an AI clone of his voice to deliver speeches from prison.
Perhaps the most effective use of this technology was in Japan, where an obscure and independent Tokyo gubernatorial candidate, Takahiro Anno, used an AI avatar to respond to 8,600 questions from voters and managed to come in fifth among a highly competitive field of 56 candidates.
Nuts and bolts
AIs have been used in political fundraising as well. Companies like Quiller and Tech for Campaigns market AIs to help draft fundraising emails. Other AI systems help candidates target particular donors with personalized messages. It’s notoriously difficult to measure the impact of these kinds of tools, and political consultants are cagey about what really works, but there’s clearly interest in continuing to use these technologies in campaign fundraising.
Polling has been highly mathematical for decades, and pollsters are constantly incorporating new technologies into their processes. Techniques range from using AI to distill voter sentiment from social networking platforms—something known as “social listening“—to creating synthetic voters that can answer tens of thousands of questions. Whether these AI applications will result in more accurate polls and strategic insights for campaigns remains to be seen, but there ispromisingresearch motivated by the ever-increasing challenge of reaching real humans with surveys.
In 2024, similar capabilities were almost certainly used in a variety of elections around the world. In the U.S., for example, a Georgia politician used AI to produce blog posts, campaign images and podcasts. Even standard productivity software suites like those from Adobe, Microsoft and Google now integrate AI features that are unavoidable—and perhaps very useful to campaigns. Other AI systems help advise candidates looking to run for higher office.
Fakes and counterfakes
And there was AI-created misinformation and propaganda, even though it was not as catastrophic as feared. Days before a Slovakian election in 2023, fake audio discussing election manipulation went viral. This kind of thing happened many times in 2024, but it’s unclear if any of it had any real effect.
In the U.S. presidential election, there was a lot of press after a robocall of a fake Joe Biden voice told New Hampshire voters not to vote in the Democratic primary, but that didn’t appear to make much of a difference in that vote. Similarly, AI-generated images from hurricane disaster areas didn’t seem to have much effect, and neither did a stream of AI-faked celebrity endorsements or viral deepfake images and videos misrepresenting candidates’ actions and seemingly designed to prey on their political weaknesses.
AI also played a role in protecting the information ecosystem. OpenAI used its own AI models to disrupt an Iranian foreign influence operation aimed at sowing division before the U.S. presidential election. While anyone can use AI tools today to generate convincing fake audio, images and text, and that capability is here to stay, tech platforms also use AI to automatically moderate content like hate speech and extremism. This is a positive use case, making content moderation more efficient and sparing humans from having to review the worst offenses, but there’s room for it to become more effective, more transparent and more equitable.
There is potential for AI models to be much more scalable and adaptable to more languages and countries than organizations of human moderators. But the implementations to date on platforms like Meta demonstrate that a lot more work needs to be done to make these systems fair and effective.
One thing that didn’t matter much in 2024 was corporate AI developers’ prohibitions on using their tools for politics. Despite market leader OpenAI’s emphasis on banning political uses and its use of AI to automatically reject a quarter-million requests to generate images of political candidates, the company’s enforcement has been ineffective and actual use is widespread.
The genie is loose
All of these trends—both good and bad—are likely to continue. As AI gets more powerful and capable, it is likely to infiltrate every aspect of politics. This will happen whether the AI’s performance is superhuman or suboptimal, whether it makes mistakes or not, and whether the balance of its use is positive or negative. All it takes is for one party, one campaign, one outside group, or even an individual to see an advantage in automation.
This essay was written with Nathan E. Sanders, and originally appeared in The Conversation.
Интернет форумите са пълни с въпроси от типа „На кого да се оплача, че в моята сграда има такъв или онакъв проблем?“. Освен да чакаме някой външен (община, законодател, инспекция и т.н.) да реши наш проблем, можем да действаме законосъобразно и сами.
В сградата, в която живеем, можем най-лесно да постигнем промяна, защото там гласът ни има голяма тежест. Необходимо е да убедим не твърде много хора, че дадена инициатива е добра или даден ремонт е необходим. А и да не забравяме, че притежаваме част от сградата – т.нар. идеални части.
Домоуправителите нямат магически способности, те помагат на собствениците да поддържат общата сграда. Всеки би могъл обаче:
Да участва в общи събрания. „Каквото решите“, „все ми е тая“, „няма смисъл“ – подобни оправдания по-скоро са причина нещата да не стават.
Да взема участие в управлението на сградата и така да се запознае как се работи на публична длъжност, която често е без доход.
Да помага на управителните органи, например със събиране на оферти, организиране на ремонти, звънене по телефони и звънци и разговори с неизрядни длъжници, идеи, труд. Или поне да не им пречи.
Няколко души притежаваме обща и скъпа вещ. Работим, за да си я позволим по десет и повече години. Логично е да я пазим, да я поддържаме и тя да запазва стойността си с времето.
Да, етажната собственост (ЕС) е такава вещ, но отношението към нея не следва тази логика. Въпреки че за мнозина да си купиш апартамент е ангажимент да изплащаш ипотека 15 и повече години, състоянието на съсобствените сгради в България не е цветущо. Достатъчно е да се огледаме около себе си. По сградата си личи колко се разбираме в малкия колектив, в който сме попаднали, и дали намираме общ език, за да защитаваме общата ни инвестиция.
Многофамилните сгради в България се регулират от Закона за управление на етажната собственост (ЗУЕС). Само в София те са около 23 000. Всяка сграда трябва да има управител (или домоуправител, както много хора са свикнали до го наричат), който се избира от Общо събрание (ОС). То е своеобразен малък парламент, в който трябва да участват всички собственици. С мнозинство се вземат решения какво да се прави на територията на общата съсобственост, а (домо)управителят трябва да изпълнява решенията.
Дотук с теорията. В реалността обаче понякога управлението на сгради се практикува дори от хора, които не са прочели ЗУЕС. Но те пък се избират от собственици, които също не са наясно с този закон. Може би ако се говори повече за ЗУЕС, повече хора ще разберат как работи, и ще се опитват да го спазват.
Дотогава споделям някои от собствените си наблюдения за сградите около нас през призмата на познанията и опита ми, свързани с темата за етажната собственост.
Проблемите
За да буксува управлението на етажните собствености, има няколко основни проблема:
Апатия
Ако живеем в многофамилна сграда, вероятно от собствен опит знаем, че трудно се събират достатъчно участници в събранията. Знае го и законодателят, който с последните промени в ЗУЕС леко намали кворума за легитимно ОС. Това, което неучастващите собственици често не осъзнават, е, че липсата на необходимото присъствие блокира работата на домоуправителя. Например как един управител да започне да събира значителна сума за ремонт на покрив, ако тя е одобрена от 13,01% (в ЗУЕС голяма част от решенията се вземат с половината присъстващи и минималният кворум е 26%)? На теория е законно, но дали управителят ще успее? Как да стартира принудително събиране от нередовни платци, ако има само 13% одобрение? Най-вероятно нередовните първо ще обвинят и наговорят „приятни“ думи на управителя, а той ще има рехава подкрепа от останалите съседи.
Законодателни несъвършенства
Макар да е ясно, че е малко вероятно в събранието да участват достатъчно присъстващи, при промените от септември 2023 г. законодателят вдигна дела гласуващи, който е необходим за избор на домоуправител. Преди той беше над 50% от присъстващите на събранието, но след измененията вече е над 50% от всички собственици.
През септември 2023 г., от една страна, се направиха няколко дигитални стъпки: въведе се имейл за комуникация с управител и съседи и дистанционно и онлайн гласуване. От друга страна обаче, се въведе ежемесечен отчет, при това задължително на хартия.
Законът е сложен
Ако някой собственик има желание да участва в управлението на сградата си, той невинаги разбира формалните изисквания и успява да води правилно документацията. Всяко юридическо лице трябва да се подчинява на счетоводните и данъчните стандарти. Но при управлението на ЕС се наблюдават значителни импровизации във воденето на документацията. Управителите и касиерите сами избират как да го правят, а това затруднява институционалната помощ, когато е необходима – например при събиране на задължения по съдебен ред.
Фирми и частни лица, управляващи ЕС
На пазара може да се намерят т.нар. професионални домоуправители – търговски фирми, които предлагат (срещу определена такса) да отменят собствениците в грижата по поддръжката на сградите, събирането на таксите и т.н. За съжаление обаче, липсва достатъчна публичност на добрите и лошите практики при тези търговци. И когато се съберат неинформираността на собствениците как работи ЗУЕС, и липсата на кворум на събрание, може сградата да се окаже „вързана“ за конкретна фирма.
На много хора им е позната ситуацията да се събират вноски за възнаграждение на фирмата и нищо да не се подобрява в сградата. Проблемът с тези фирми е в топ 4 на получените становища от Министерството на регионалното развитие и благоустройството при обсъждането на промените в ЗУЕС от 2019–2020 г. За съжаление, след промените на закона през 2023 г. няма голямо подобрение за този казус. По-скоро новата редакция на закона доста ще затрудни най-малките играчи – частни лица, управляващи 3–4 близки входа или сгради. Тези домоуправители се препоръчват от „уста на уста“ и са от най-съвестните.
Ще бъде по-трудно и за най-малките фирми с един-двама служители. По-сложно става и за управителите собственици, чийто избор вече трябва да става с над 50% от всички собственици. Административната трудност за най-дребните играчи не означава обаче подобряване на услугата в сектора.
Пасивност в Столичната община
Столичната община (СО) няма пълни данни как се управляват сградите. Не разполага с данни и за качеството на сградите. Липсата на информация ѝ пречи да работи заедно с ЕС за подобряване на околоблоковото пространство например. Ала същевременно Общината не поема инициативата това да се промени.
Въпреки че ЗУЕС е обект на много критики, той подчертава ролята на местната власт като основен помощник на етажните собствености. Кметът е задължен да назначи управител, ако няма такъв, издава актове за административни нарушения в сградата, може да разпореди неотложен ремонт и т.н. Общината обаче невинаги изпълнява тези свои функции ефективно.
Ако заеме по-активна позиция в процесите, засягащи ЕС, Общината може значително да подобри тяхното функциониране и да допринесе за създаването на по-привлекателна жизнена среда за жителите на многофамилните жилищни сгради.
Ето няколко предложения как СО би могла активно да подобри ставащото на територията на ЕС и в междублоковите пространства:
Комуникация, комуникация, комуникация. Една от основните причини за ниската активност в общите събрания е липсата на информираност сред собствениците какви са техните права и отговорности. Общината би могла да играе по-активна роля в повишаването на обществената осведоменост чрез информационни кампании, семинари и онлайн ресурси, обясняващи ползите от активното участие в управлението на ЕС и на стъпките, включени в процеса. Тя може да организира редовни срещи или форуми, на които собствениците и мениджърите на ЕС да имат възможност да обсъждат своите притеснения и да търсят решения заедно.
Опростяване на процедурите. Законодателството за ЕС е сложно и объркващо и обезсърчава собствениците да участват активно в управлението. Би било полезно да се преразгледат и опростят съществуващите разпоредби, за да станат по-разбираеми и по-достъпни за всички собственици. Това може да включва разработването на ясни насоки или ръководства стъпка по стъпка за различните процеси – например свикване на ОС, вземане на решения и разрешаване на спорове. СО би могла да организира проучване и да предложи подходящи законодателни промени.
Подкрепа и насърчаване на добре управлявани сгради. Смисълът на подобна програма би бил да стимулира ЕС да подобрят своята ефективност, да поддържат сградите си и да създават по-приятна жизнена среда. За да участва в програмата, една ЕС трябва да изпълни определени критерии, свързани с управлението на сградата, поддръжката и спазването на законовите изисквания. Ето няколко примера за такива стимули:
Намаление на цената на картите за градски транспорт.
Преференциален достъп до спортни съоръжения – например плувни басейни, фитнес зали и спортни зали.
Поддръжка на зелените площи – Общината може да предложи съдействие за озеленяване на околоблоковото пространство – да предостави растения, пейки, детски съоръжения и др.
Други общински услуги – Общината може извърши анализ кои общински услуги биха могли да се предложат с отстъпка или безплатно на добре управлявани ЕС. Примерите може да включват услуги за управление на отпадъци, ремонти на обществени пространства, организиране на събития и т.н.
Събиране на данни и наблюдение. За да помогне на етажните собствености да стигнат до решение кое трябва да се подобри, и да вземат информирани решения, СО може да събира и споделя данни за състоянието на сградите, включително тяхната енергийна ефективност, инфраструктура, техническо състояние, ниво на поддръжка, събираемост на такси, текущи такси. Това ще позволи на Общината да разбере по-добре нуждите на етажните собствености да планират и предприемат инициативи за подобряване на състоянието си.
Ангажиране на общността. Включването на местните общности в усилията за подобряване на ЕС може да помогне за изграждането на чувство за общност и споделена отговорност. СО може да си партнира с квартални групи, училища и местни организации, за да популяризира значението на добре управляваните етажни собствености и да предостави възможности хората да допринесат за каузата.
Приоритизация. По данни на Националния статистически институт в столицата има близо 800 000 жилища и значителна част от тях са в режим на ЕС. Ако предположим, че един апартамент струва средно 100 000 евро, това означава, че жилищният актив само в София е поне 80 млрд. евро, което се доближава до размера на годишния брутен вътрешен продукт на държавата. А най-разпространената общинска услуга на експертите на СО за този доста скъп актив е… да регистрират домоуправители и да издават удостоверения. Ако СО играе по-активна роля в поддържането на жилищния фонд, ще повлияе върху подобряването на качеството на живот на гражданите и тяхната удовлетвореност от средата, в която живеят. Защото това, което виждаме най-често, когато излезем от къщи, са общият коридор, фоайе, асансьор и пространството около блока.
Освен идеите по-горе има и редица други неща, за които СО може съдейства.
Например за по-ефективно събиране на вземания от длъжници – да речем, чрез вписване на задълженията към ЕС при издаване на данъчна оценка. Или за извършване на неотложни ремонти по чл. 49 от ЗУЕС – защо за тази цел не се създаде фонд в СО, който се захранва от принудително събраните от собствениците средства за извършените ремонти? Или за спазване на санитарно-хигиенни норми – съдействие при случаи на събирачи на пречещи на обитателите на сградата животни и вехтории; миризми от съседи или търговски обекти и др. Или насочване към психолози и медиатори при конфликтни ситуации. И т.н.
Чрез прилагането на подобни мерки СО може да изиграе ключова роля в подпомагането на етажните собствености да преодолеят настоящите предизвикателства и да създадат по-приветлива, удобна и добре поддържана жилищна среда за над милион жители на София.
В настоящата ни съвместна поредица с „Екипът на София“ обсъждаме планирането, озеленяването, архитектурата, инфраструктурата, мобилността и още много други градски теми, описваме добрите примери и търсим възможните решения за подобряването на качеството на живот в нашите градове.
I hit a point where I just didn’t like this website any more. It was too… stuffy. Posts kept getting longer, more elaborate, more time-consuming to write. I didn’t recognize the tone any more, and when I look back at older posts, those are way snarkier than they need to be. I think I was trying to be taken seriously-but-not-too-seriously, and the voice that developed as a result was just really weird.
I kept looking at this blog and thinking… who is this? Who wrote this? And who is supposed to write more of this?
The previous design was based around “keep looking like sort of like the default Octopress theme I used to have”. I don’t think that was a great design philosophy, not least of all because I stopped using Octopress in 2012, and Octopress itself has been abandoned since 2015. But it was also just… beige. I think I was hoping that brown-ish would be reminiscent of Eevee colors?
So I redid it from scratch, based on the new design philosophy of “I like it”. And you know what? I like it! I hope you like it too. But also, I don’t care too much if you don’t, because it’s for me!
Also, hey, did you know CSS can do all kinds of crazy stuff now? Like nesting blocks? This blog used to use SCSS! Now it doesn’t need to! And I barely had to change anything! Maybe there’s a post in there.
You might need a recent browser, but you should be using a recent browser anyway.
My time on Cohost, which allowed near-arbitrary inline HTML and CSS, has rekindled a joy in doing stupid tricks with CSS, and so I’ve glued together a mountain of stupid tricks to make something more playful and distinct. Also I can draw better now than I could a decade ago, so I flexed those muscles a bit, too.
One thing I do slightly lament is that my games used to be above the fold (at least on my screen), and now they’re not. But I think this design actually rewards… scrolling down? So hopefully that helps. Not like I’m collecting metrics or anything.
I’ve intended to do this for ages. The old landing page contained an exhaustive list of… most things I’ve made or worked on, which made it kind of a cluttered mess. Now that exhaustive list has a real home as the landing page for c.eev.ee. I’ve been using this to host stuff (like Lexy’s Labyrinth) for ages, but the root page has been a 403 that whole time. Now it’s not! Wow!
Also: a list of my puzzles! There aren’t too many yet, but maybe there will be??
Pelican has both “articles”, which are dated, and “pages”, which are not. I looked over a lot of my old posts in the course of this redesign, and a lot of them are either out of date w.r.t. technical information, about an event that was only interesting for a brief time, or just… unmaintained?
Which all makes sense for something that has a date, right? Like, Wikipedia articles don’t have a date. Those are assumed to be reasonably current. And there’s something a little sad about writing a very lengthy post with a lot of details about something, and then watching it sink into the ocean of time. But keeping a post with “2015” in the URL up-to-date indefinitely doesn’t seem quite right.
So I’m taking a crack at “pages”. I expect the presentation will change a bit as I accumulate more, but I’ve seeded the idea with a couple starter pages:
Two pure-CSS toys/puzzles that were originally Cohost CSS crimes, now tidied up and with full
explanations: Lights Out and Rush Hour.
A lengthy list of variant sudoku types with full rules and examples, something that I hadn’t seen anywhere else.
At some point I put the category in the URL, so “normal” blog posts were at /blog/foo, whereas my dev log posts were at /dev/foo. I don’t know why I thought that was a good idea, and it makes it annoying to reshuffle the categories, so I’ve collapsed everything back into /blog.
There are redirects up the wazoo so this shouldn’t matter to anyone. But if you find a link to my site that 404s, I must’ve missed a redirect, so, please let me know.
The cool news is that instead of reverse-chrono categories, there’s now a much better way to find a post you’re looking for: I made a full list of all my writing! Enjoy. But don’t read anything from before 2015.
I probably forgot a lot of little things, and the layout is still a bit work-in-progress on very small screens. I’m also not entirely sure how to convey the distinction between articles/pages at a glance, and I don’t have a real name for the c.eev.ee page, so it’s called something different everywhere it appears.
Feel free to send me your nitpicks; I’d like this design to be more actively maintained than the old one was.
Coming up next: Posts?? More posts?????? Remember when I wrote posts????????
The AWS Glue Data Catalog now automates generating statistics for new tables. These statistics are integrated with the cost-based optimizer (CBO) from Amazon Redshift Spectrum and Amazon Athena, resulting in improved query performance and potential cost savings.
Queries on large datasets often read extensive amounts of data and perform complex join operations across multiple datasets. When a query engine like Redshift Spectrum or Athena processes the query, the CBO uses table statistics to optimize it. For example, if the CBO knows the number of distinct values in a table column, it can choose the optimal join order and strategy. These statistics must be collected beforehand and should be kept up to date to reflect the latest data state.
Previously, creating statistics for Iceberg tables in the Data Catalog required you to continuously monitor and update configurations for your tables. You had to do undifferentiated heavy lifting to do the following:
Discover new tables with specific data table formats (such as Parquet, JSON, CSV, XML, ORC, ION) and specific transactional data table formats such as Iceberg and their individual bucket paths
Determine and set up compute tasks based on scan strategy (sampling percentage and schedules)
Set up event notification systems to understand changes in data lakes
Set up specific optimizer configuration-based query performance and storage improvement strategies
Set up a scheduler or build your own event-based compute tasks with setup and teardown
Now, the Data Catalog lets you generate statistics automatically for updated and created tables with a one-time catalog configuration. You can get started by selecting the default catalog on the Lake Formation console and enabling table statistics on the table optimization configuration tab. As new tables are created, the number of distinct values (NDVs) are collected for Iceberg tables, and additional statistics such as the number of nulls, maximum, minimum, and average length are collected for other file formats such as Parquet. Redshift Spectrum and Athena can use the updated statistics to optimize queries, using optimizations such as optimal join order or cost-based aggregation pushdown. The AWS Glue console provides you visibility into the updated statistics and statistics generation runs.
Now, data lake administrators can configure weekly statistics collection across all databases and tables in their catalog. When the automation is enabled, the Data Catalog generates and updates column statistics for all columns in the tables on a weekly basis. This job analyzes 20% of records in the tables to calculate statistics. These statistics can be used by Redshift Spectrum and Athena CBO to optimize queries.
Furthermore, this new feature provides the flexibility to configure automation settings and scheduled collection configurations at the table level. Individual data owners can override catalog-level automation settings based on specific requirements. Data owners can customize settings for individual tables, including whether to enable automation, collection frequency, target columns, and sampling percentage. This flexibility allows administrators to maintain an optimized platform overall, while enabling data owners to fine-tune individual table statistics.
In this post, we discuss how the Data Catalog automates table statistics collection and how you can use it to enhance your data platform’s efficiency.
Enable catalog-level statistics collection
The data lake administrator can enable catalog-level statistics collection on the Lake Formation console. Complete the following steps:
On the Lake Formation console, choose Catalogs in the navigation pane.
Select the catalog that you want to configure, and choose Edit on the Actions menu.
The command calls the AWS Glue UpdateCatalog API, which takes in a CatalogProperties structure that expects the following key-value pairs for catalog-level statistics:
ColumnStatistics.RoleArn – The IAM role Amazon Resource Name (ARN) to be used for all jobs triggered for catalog-level statistics
ColumnStatistics.Enabled – A Boolean value indicating whether the catalog-level settings are enabled or disabled
Callers of UpdateCatalog must have UpdateCatalog IAM permissions and be granted ALTER on CATALOG permissions on the root catalog if using Lake Formation permissions. You can call the GetCatalog API to verify the properties that are set to your catalog properties. For the required permissions used by the role passed, see Prerequisites for generating column statistics.
By following these steps, catalog-level statistics collection is enabled. AWS Glue then automatically updates statistics for all columns in each table, sampling 20% of records on a weekly basis. This allows data lake administrators to effectively manage the data platform’s performance and cost-efficiency.
View automated table-level settings
When catalog-level statistics collection is enabled, when an Apache Hive table or Iceberg table is created or updated using the AWS Glue CreateTable or UpdateTable APIs through the AWS Glue console, AWS SDK, or AWS Glue crawlers, an equivalent table level setting is created for that table.
Tables with automatic statistics generation enabled must follow one of following properties:
HIVE table formats such as Parquet, Avro, ORC, JSON, ION, CSV, and XML
Apache Iceberg table format
After a table has been created or updated, you can confirm that a statistics collection setting has been set by checking the table description on the AWS Glue console. The setting should have the Schedule property set as Auto and Statistics configuration set as Inherited from catalog. Any table setting with the following settings is automatically triggered by AWS Glue internally.
The following is an image of a Hive Table where catalog-level statistics collection has been applied and statistics have been collected:
The following is an image of a Iceberg Table where catalog-level statistics collection has been applied and statistics have been collected:
Configure table-level statistics collection
Data owners can customize statistics collection at the table level to meet specific needs. For frequently updated tables, statistics can be refreshed more often than weekly. You can also specify target columns to focus on those most commonly queried.
Moreover, you can set what percentage of table records to use when calculating statistics. Therefore, you can increase this percentage for tables that need more precise statistics, or decrease it for tables where a smaller sample is sufficient to optimize costs and statistics generation performance.
These table-level settings can override the catalog-level settings previously described.
To configure table-level statistics collection on AWS Glue console, complete the following steps:
On the AWS Glue console, choose Databases under Data Catalog in the navigation pane.
Choose a database to view all available tables (for example, optimization_test).
Choose the table to be configured (for example, catalog_returns).
Go to Column statistics and choose Generate on schedule.
In the Schedule section, choose the frequency from Hourly, Daily, Weekly, Monthly and Custom (cron expression). In this example, for Frequency, choose Daily.
Under Advanced configuration, for Security configuration, optionally choose your security configuration to enable at-rest encryption on the logs pushed to CloudWatch.
For Sample rows, enter 100 as the percentage of rows to sample.
Choose Generate statistics.
In the table description on the AWS Glue console, you can confirm that a statistics collection job has been scheduled for the specified date and time.
By following these steps, you have configured table-level statistics collection. This allows data owners to manage table statistics based on their specific requirements. Combining this with catalog-level settings by data lake administrators enables securing a baseline for optimizing the entire data platform while flexibly addressing individual table requirements.
You can also create a column statistics generation schedule through the AWS CLI:
The required parameters are database-name, table-name, and role. You can also include optional parameters such as schedule, column-name-list, catalog-id, sample-size, and security-configuration. For more information, see Generating column statistics on a schedule.
Conclusion
This post introduced a new feature in the Data Catalog that enables automated statistics collection at the catalog level with flexible per-table controls. Organizations can effectively manage and maintain up-to-date column-level statistics. By incorporating these statistics, CBO in both Redshift Spectrum and Athena can optimize query processing and cost-efficiency.
Try out this feature for your own use case, and let us know your feedback in the comments.
About the Authors
Sotaro Hikita is an Analytics Solutions Architect. He supports customers across a wide range of industries in building and operating analytics platforms more effectively. He is particularly passionate about big data technologies and open source software.
Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.
Kyle Duong is a Senior Software Development Engineer on the AWS Glue and AWS Lake Formation team. He is passionate about building big data technologies and distributed systems.
Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.
In 2024, Thanksgiving (November 28), Black Friday (November 29), and Cyber Monday (December 2) significantly impacted Internet traffic, similar to trends seen in 2023 and previous years. This year, Thanksgiving in the US drove a 20% drop in daily traffic compared to the previous week, with a notable 33% dip at 15:45 ET. In contrast, Black Friday and Cyber Monday drove traffic spikes. But how global is this trend, and do attacks increase during Cyber Week?
At Cloudflare, we manage and protect a substantial amount of traffic for our customers, providing a unique vantage point to analyze traffic and attack patterns across the Internet. This perspective reveals insights like Cyber Monday being the busiest Internet traffic day of 2024 globally, followed by Black Friday, with patterns varying across countries. Notably, global HTTP request volume on Cyber Monday 2024 was 36% higher than 2023, with 5% of that traffic blocked as potential attacks.
For this analysis, we examined anonymized and aggregated HTTP requests and DNS queries across our network to uncover key patterns. Cyber Monday, December 2, was the day with peak traffic, and key findings for that day include:
Cloudflare processed a peak of 99.8 million HTTP requests per second at 15:33 UTC on Cyber Monday, December 2.
Cloudflare handled approximately 5.4 trillion daily requests on Cyber Monday, with blocked potential attacks comprising around 5% of all traffic. This was higher than the 5.1 trillion daily requests on Black Friday, where 6% of request traffic consisted of blocked potential attacks.
Daily global HTTP request volume on Cyber Monday 2024 (December 2) increased by 36% compared to Cyber Monday 2023. In comparison, Cyber Monday 2023 had shown a 27% increase over Cyber Monday 2022.
Ranking Cyber Week daily Internet traffic
This year’s trends, like those observed in previous years, show how Internet traffic typically peaks in late November but tends to drop in December. In 2024, Cyber Monday was again the busiest day for global Internet traffic. However, Black Friday didn’t make the Top 3, as Sunday, December 1, and Tuesday, November 26, saw higher traffic. Black Friday ranked #5, coming behind November 21.
Note: On December 1, 2024, a customer-specific software update event contributed to the increased Internet traffic observed that day, including at the country level.
Highest Internet traffic days, worldwide
#1 Cyber Monday, December 2, 2024
#2 Sunday, December 1, the day before Cyber Monday
#3 Tuesday, November 26, 2024
In the US, the ranking was similar, with Cyber Monday, Sunday, and Black Friday being the busiest days for Internet traffic. On Cyber Monday, traffic was 12% higher than the previous week and 57% higher than Cyber Monday 2023.
Highest Internet traffic days, United States
#1 Cyber Monday, December 2
#2 Sunday, December 1
#3 Black Friday, November 29
Additionally, most US states show a similar trend, with Cyber Monday generating the most traffic, followed by Sunday, December 1, and Black Friday, November 29. Arizona, West Virginia, and Arkansas saw increases in traffic of over 20% compared to the previous week. Almost all other states experienced traffic increases exceeding 10%, including some of the most populous ones like California (11%), Florida (11%), and New York (11%).
In looking at just traffic to Shopping and Retail sites based in the US that use Cloudflare, Cyber Monday recorded the highest traffic, followed by Black Friday and the Black Friday weekend. Traffic to these sites increased significantly during Cyber Week, starting on Monday, November 25, with a 7% increase compared to the previous week and a 57% jump compared to the first week of November.
Black Friday goes mobile, Cyber Monday goes desktop
During Thanksgiving Day, mobile usage in the US increased significantly, with mobile device traffic accounting for 51.7% of all traffic, compared to 42.4% the previous week. The trend intensified on Black Friday, with mobile’s share peaking at 51.9% (up from 43.9% the prior Friday) and reaching a similar level on Saturday, November 30, at 52%. However, Cyber Monday saw a shift to desktop use, with mobile device share dropping to 43.4%, lower than the previous Monday. This mirrors a similar trend observed in 2023.
These patterns suggest that Black Friday shopping in the US often involves more out of home/office activities, with people relying on mobile devices for Internet access while on the go, whereas the opposite tends to occur on Cyber Monday, a day when many return to work and school in the US.
How are other countries impacted by Cyber Week?
Internationally, a trend of peak Internet traffic in November is observed in most countries, as highlighted in our 2023 Year in Review. This trend is likely linked to colder weather in the Northern Hemisphere, where approximately 87% of the world’s population resides, as well as holidays and shopping periods, among other factors.
Here’s a table summarizing the November and early December days with the most traffic, where Cyber Week plays a significant role.
Highest Internet traffic days
UK
#1 Black Friday, November 29
#2 Cyber Monday, December 2
#3 Sunday, December 1 (Black Friday weekend)
Canada
#1 Cyber Monday, December 2
#2 Black Friday, November 29
#3 Sunday, December 1 (Black Friday weekend)
Germany
#1 Sunday, December 1 (Black Friday weekend)
#2 Black Friday, November 29
#3 Cyber Monday, December 2
Mexico
#1 Cyber Monday, December 2
#2 Wednesday, November 27
#3 Tuesday, November 26
France
#1 Sunday, December 1 (Black Friday weekend)
#2 Cyber Monday, December 2
#3 Wednesday, November 27
Brazil
#1 Tuesday, November 26
#2 Cyber Monday, December 2
#3 Thursday, November 21
Spain
#1 Sunday, December 1 (Black Friday weekend)
#2 Cyber Monday, December 2
#3 Tuesday, November 26
Australia
#1 Black Friday, November 29
#2 Cyber Monday, December 2
#3 Sunday, December 1 (Black Friday weekend)
Egypt
#1 Wednesday, November 27
#2 Sunday, December 1 (Black Friday weekend)
#3 Sunday, November 24
Singapore
#1 Friday, November 22
#2 Cyber Monday, December 2
#3 Tuesday, November 26
India
#1 Cyber Monday, December 2
#2 Black Friday, November 29
#3 Sunday, December 1 (Black Friday weekend)
Turkey
#1 Sunday, December 1 (Black Friday weekend)
#2 Cyber Monday, December 2
#3 Singles’ Day, November 10-11
Saudi Arabia
#1 Sunday, December 1 (Black Friday weekend)
#2 Saturday, November 30 (Black Friday weekend)
#3 Cyber Monday, December 2
South Africa
#1 Wednesday, November 27
#2 Tuesday, November 26
#3 Black Friday, November 29
Countries like the Philippines (where Singles’ Day was the top shopping day again this year), Japan, South Korea, Thailand, and Indonesia (where Cyber Monday ranked second this year) show increased traffic in October and November compared to other months. However, they do not exhibit an obvious increase in traffic during Cyber Week.
As noted earlier, Singles’ Day (November 11), a major Asian shopping event, ranked among the Top 3 traffic days in Turkey, the Philippines, and other countries.
E-commerce DNS trends
Aggregated data from our 1.1.1.1 resolver reveals category-specific DNS traffic growth to E-commerce sites, showing a steady increase throughout November, similar to the overall Internet traffic trends.
In the US, E-commerce DNS traffic in November 2024 followed a similar pattern compared to 2023. Black Friday (November 29) ranked as the top day for DNS traffic in the E-commerce category, followed closely by Cyber Monday and Tuesday, November 26. This aligns more closely with overall US Internet traffic trends, where Cyber Monday ranked #1.
Also in the E-commerce category, DNS traffic on Black Friday peaked between 15:00 and 18:00 ET (13:00 and 15:00 PT), with an 18% increase at 18:00 ET compared to the previous week. On Cyber Monday, peak traffic occurred later, from 20:00 to 22:00 ET (17:00 to 19:00 PT).
A glimpse into Europe’s DNS E-commerce trends
The UK showed a similar trend in DNS traffic to E-commerce sites, mirroring its Internet traffic patterns, and following the same pattern as 2023. In 2024, Black Friday (November 29) ranked #1, followed by Cyber Monday (December 2), and Thursday, November 21.
In Australia, Saturday, November 30 (the day after Black Friday), was the top day for E-commerce DNS traffic, followed by Cyber Monday and Black Friday. Canada followed a similar trend, with Black Friday ranking highest, followed by Cyber Monday.
In Germany, the busiest E-commerce day was Thursday, November 21, a week before Black Friday, followed by Black Friday (November 29) and Monday, November 25. Cyber Monday did not make the top three, consistent with 2023.
In France, Black Friday remained the top E-commerce day, as in 2023, followed by Cyber Monday (December 2) and Thursday, November 21.
Low-cost and second-hand DNS trends
Focusing on the US again, so-called “low-cost” E-commerce sites (which include recent entrants like Temu and fast-fashion brands) have become increasingly popular, and experienced more DNS traffic in the days leading up to Black Friday and Thanksgiving, specifically November 26 and 27. Cyber Monday ranked third.
As observed last year, second-hand shopping sites (ones that offer previously used items) in the US gained more momentum and DNS traffic during the two weeks before Black Friday week. Traffic to these sites peaked on November 12, with Cyber Monday coming in as a close second.
Growth of cyber threats in November
DDoS (distributed denial-of-service) attacks remain a common tactic for disrupting Internet properties. Our data shows that Shopping and Retail sites in the United States protected by Cloudflare experienced a significant rise in DDoS activity on Cyber Monday. On that day, 7% of all traffic in this category was mitigated as DDoS attacks, with an additional 8% flagged as potential threats.
More broadly, DDoS activity targeting the US in general (not limited to E-commerce) also spiked during Black Friday week. Starting November 24, the share blocked as DDoS attacks rose sharply, peaking at over 2% of all traffic on November 25. Across the entire Cyber Week, there was a 41% increase in blocked DDoS attack requests compared to the previous week.
Email threat trends around “Black Friday” and “Cyber Monday”
From a cybersecurity perspective, trending events, topics, and individuals often trigger spikes in email traffic, including malicious, phishing, and spam messages. This was evident during the Paris 2024 Olympics, the US elections, and shopping periods like Black Friday and Cyber Monday. Between November 1 and December 2, 2024, Cloudflare’s Cloud Email Security service processed nearly 24 million emails mentioning “Black Friday” or “Cyber Monday” in the subject. Of those, 19.4 million referenced “Black Friday” while 4.2 million mentioned “Cyber Monday”, with 76% (3.2 million) of the Cyber Monday emails sent on December 2, 2024.
During this period, “Black Friday” emails were not only higher volume but also showed higher percentages of spam (10.8%) and malicious content (0.9%) compared to emails mentioning “Cyber Monday” in the subject, which had 1.8% spam and 0.2% malicious content.
In the next chart, we focus on emails with “Black Friday” in the subject, given that it generated the highest percentage of spam and malicious emails. Spam emails peaked in mid-November, making up 29% of all emails, and reached 26% on Cyber Monday. Malicious email percentages were also higher in mid-November, with 3% recorded on November 14, before Black Friday week.
The busiest day for “Black Friday” emails was November 29, Black Friday itself, with 4.1 million emails, followed by Saturday, November 30 (1.5 million), and Wednesday, November 27 (1.4 million).
Wrap up
Internet traffic trends during Black Friday and Cyber Monday show varying patterns globally and regionally. Cyber Monday leads in traffic overall, followed closely by Black Friday. While the US and Canada share similar trends, countries like the UK, Germany, and Australia saw traffic higher on Black Friday than Cyber Monday. In most countries, activity also increased in the days leading up to Black Friday.
On the cybersecurity front, DDoS attacks were more noticeable during Cyber Week in 2024, especially targeting shopping-related sites.
The Lorex 2K Indoor Wi-Fi Security Camera is a consumer security device that provides cloud-based video camera surveillance capabilities. This device was a target at the 2024 Pwn2Own IoT competition. Rapid7 developed an unauthenticated remote code execution (RCE) exploit chain as an entry for the competition. On November 25, 2024, Lorex released a firmware update to resolve the five vulnerabilities that comprise the exploit chain reported by Rapid7. As of December 3, 2024, we are disclosing these issues publicly in coordination with the vendor.
Technical analysis
A detailed technical analysis for the exploit chain described in this blog can be found in Rapid7’s whitepaper here.
The accompanying source code for the exploit chain can be found here.
The exploit chain consists of five distinct vulnerabilities, which operate together in two phases to achieve unauthenticated RCE. The five vulnerabilities are listed below.
CVE
Description
Affected Component
CVSS
CVE-2024-52544
An unauthenticated attacker can trigger a stack-based buffer overflow.
Phase 1 performs an authentication bypass, allowing a remote unauthenticated attacker to reset the device’s admin password to a password of the attacker’s choosing. This phase leverages an unauthenticated stack-based buffer overflow, and an unauthenticated out-of-bounds (OOB) heap read vulnerability. The OOB heap read allows an attacker to leak secrets stored in the device’s memory that are required to compute a special code value; this code value is required for an administrator password reset to be performed. A null pointer dereference vulnerability is leveraged to force the device to reboot in order to allow the next phase to complete.
Phase 2 achieves remote code execution by leveraging the auth bypass in phase 1 to perform an authenticated stack-based buffer overflow and execute an operating system (OS) command with root privileges. This capability is then leveraged to write a file to disk and, in turn, bypass the device’s code signing enforcement in order to execute arbitrary native code. Finally, the exploit will execute a reverse shell payload to give the remote attacker a root shell on the target device.
An overview of the two phases chained together can be seen below.
Impact
A remote unauthenticated attacker can leverage CVE-2024-52544, CVE-2024-52545, and CVE-2024-52546 (Phase 1) to reset a target device’s admin password, to a password of the attacker’s choosing. With valid admin credentials, an attacker can then either view the live video and audio feed from the device, or proceed to leverage CVE-2024-52547 and CVE-2024-52548 (Phase 2) to achieve remote code execution with root privileges on the target device.
The below table lists the affected devices and firmware versions.
Device
Firmware
W461AS-EG
2.800.00LR000.0.R.210907
W462AQ-EG
2.800.00LR000.0.R.210907
W461AS
2.800.00LR000.0.R.210730
W462AQ
2.800.00LR000.0.R.210730
W461AS-EG S2
2.800.0000000.3.R.20220331
W462AC-EG S2
2.800.0000000.3.R.20220331
W461AS
2.800.0000000.3.R.202203
W462AQ
2.800.0000000.3.R.202203
W461ASC
2.800.030000000.3.R
Credit
These vulnerabilities were discovered by Stephen Fewer, Principal Security Researcher at Rapid7 and are being disclosed in accordance with Rapid7’s vulnerability disclosure policy.
Vendor Statement
The following statement has been provided by the vendor.
Lorex Technology is dedicated to delivering the highest standards of protection and privacy for our customers and will collaborate with esteemed security experts to proactively identify and address potential vulnerabilities. In collaboration with Rapid7, we’ve been advised about one of our security cameras and successfully implemented a firmware update, which has fully resolved the identified security vulnerability.
Remediation
The following remediation steps have been provided by the vendor.
Our product team has decided to push the mandatory firmware updates to the devices. Upon opening Lorex app, users will be presented with the firmware update notice. User must accept the firmware update, and they cannot decline or postpone the firmware update. Camera will then flash new firmware and reboot. We advise that the users would not power down the camera during the firmware update. Once the camera reboots, the user can confirm that they have the latest version of firmware: V2.800.0000000.8.R.20241111
Disclosure timeline
October 29, 2024: Rapid7 contacts the vendor about the issues in this blog; vendor acknowledges. October 31, 2024: Rapid7 shares disclosure write-up with the vendor. November 4, 2024: Vendor indicates a patch is in development. November 12, 2024: Rapid7 provides CVEs IDs for the issues identified. November 13, 2024: Vendor verifies patch schedule. November 19, 2024: Rapid7 and the vendor agree to a December 3, 2024 coordinated disclosure date. December 3, 2024: This disclosure.
The traditional structure of a compiler forms a pipeline — parsing,
type-checking, optimization, and code-generation, usually in that order. But
modern programming languages have requirements that are ill-suited to such a
design. Increasingly, compilers are moving toward other designs in
order to support incremental compilation and low-latency responses for uses
like integration into IDEs. Rust has, for the last eight years, been pursuing a
particularly unusual design; in that time
compile times have
substantially improved, but there’s still more work to be done.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
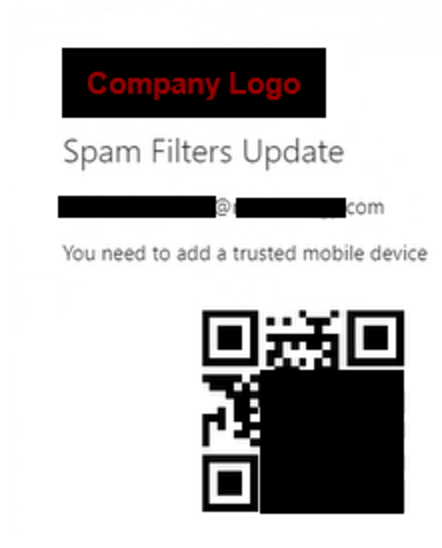
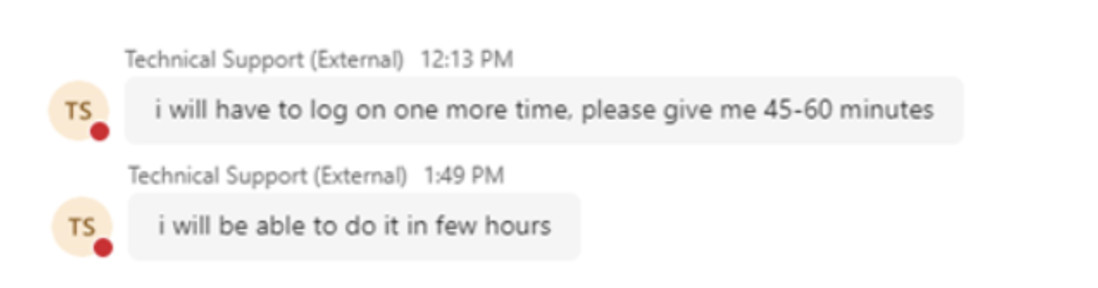
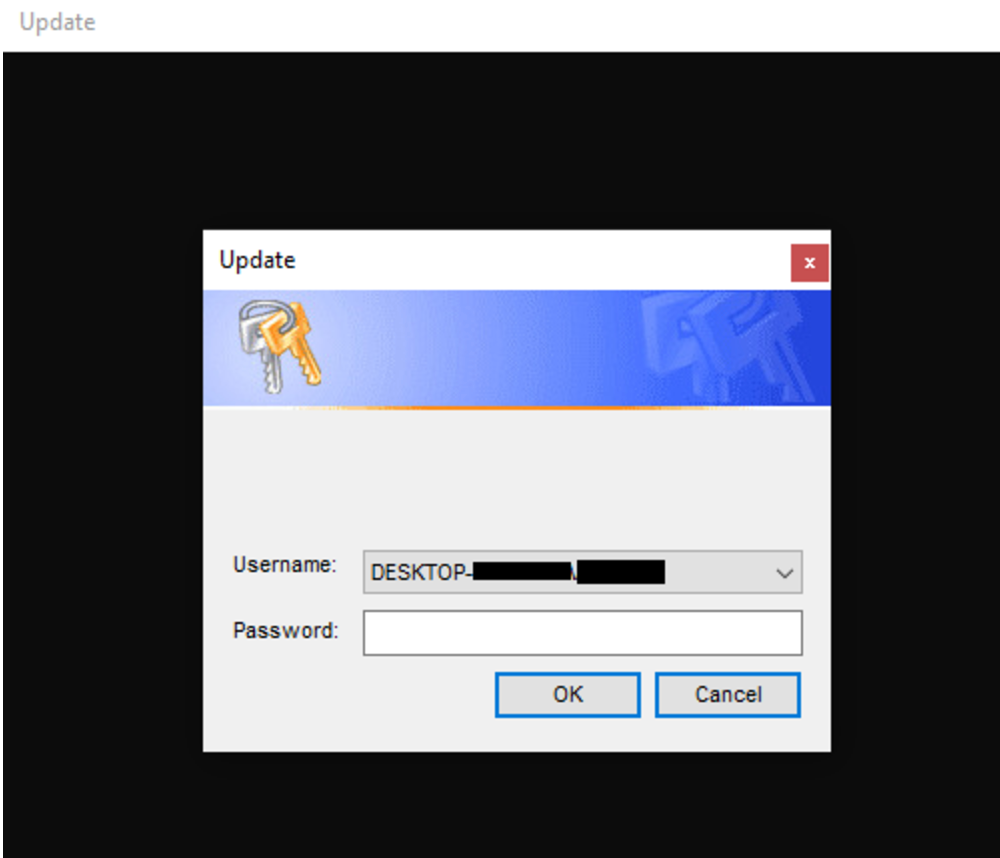
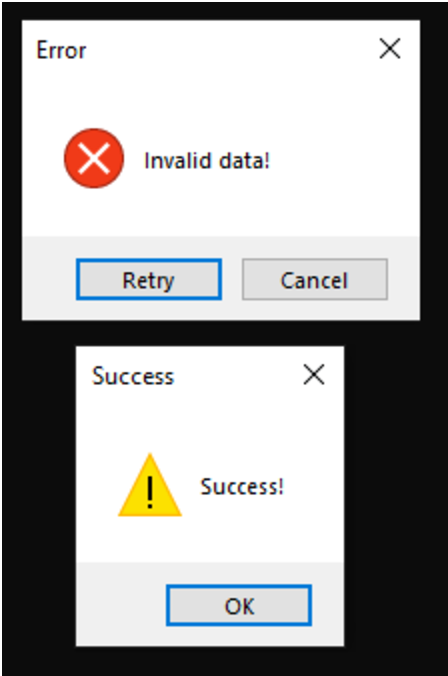
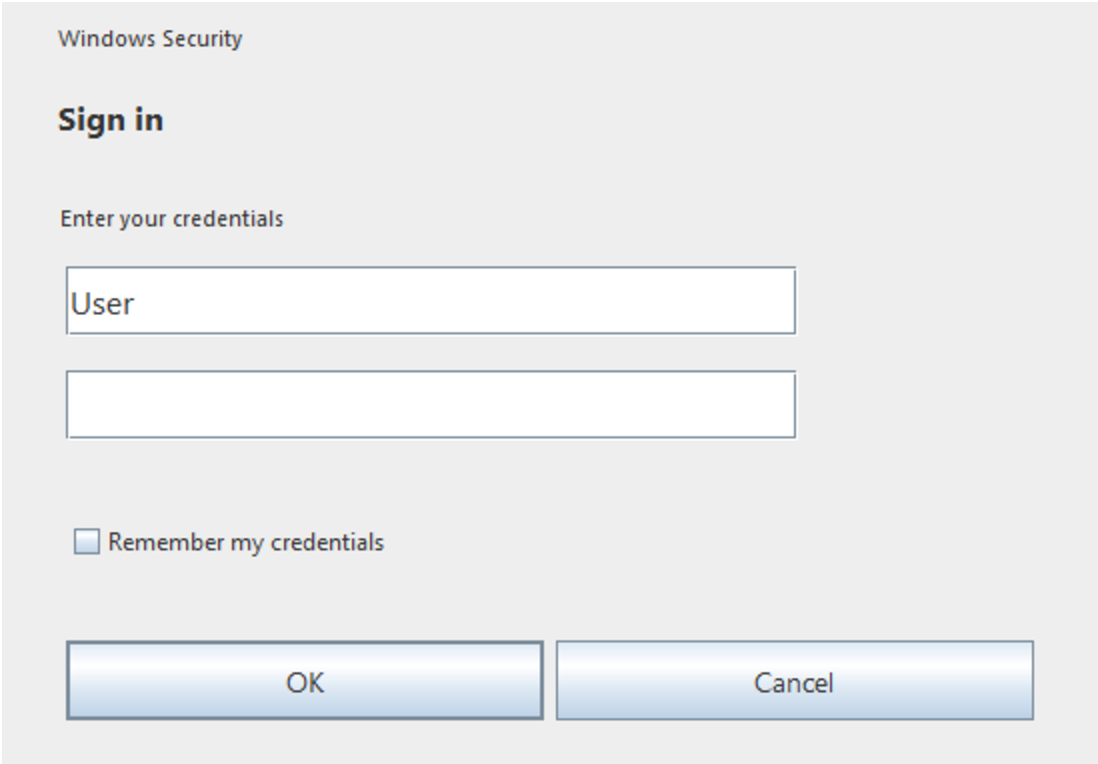
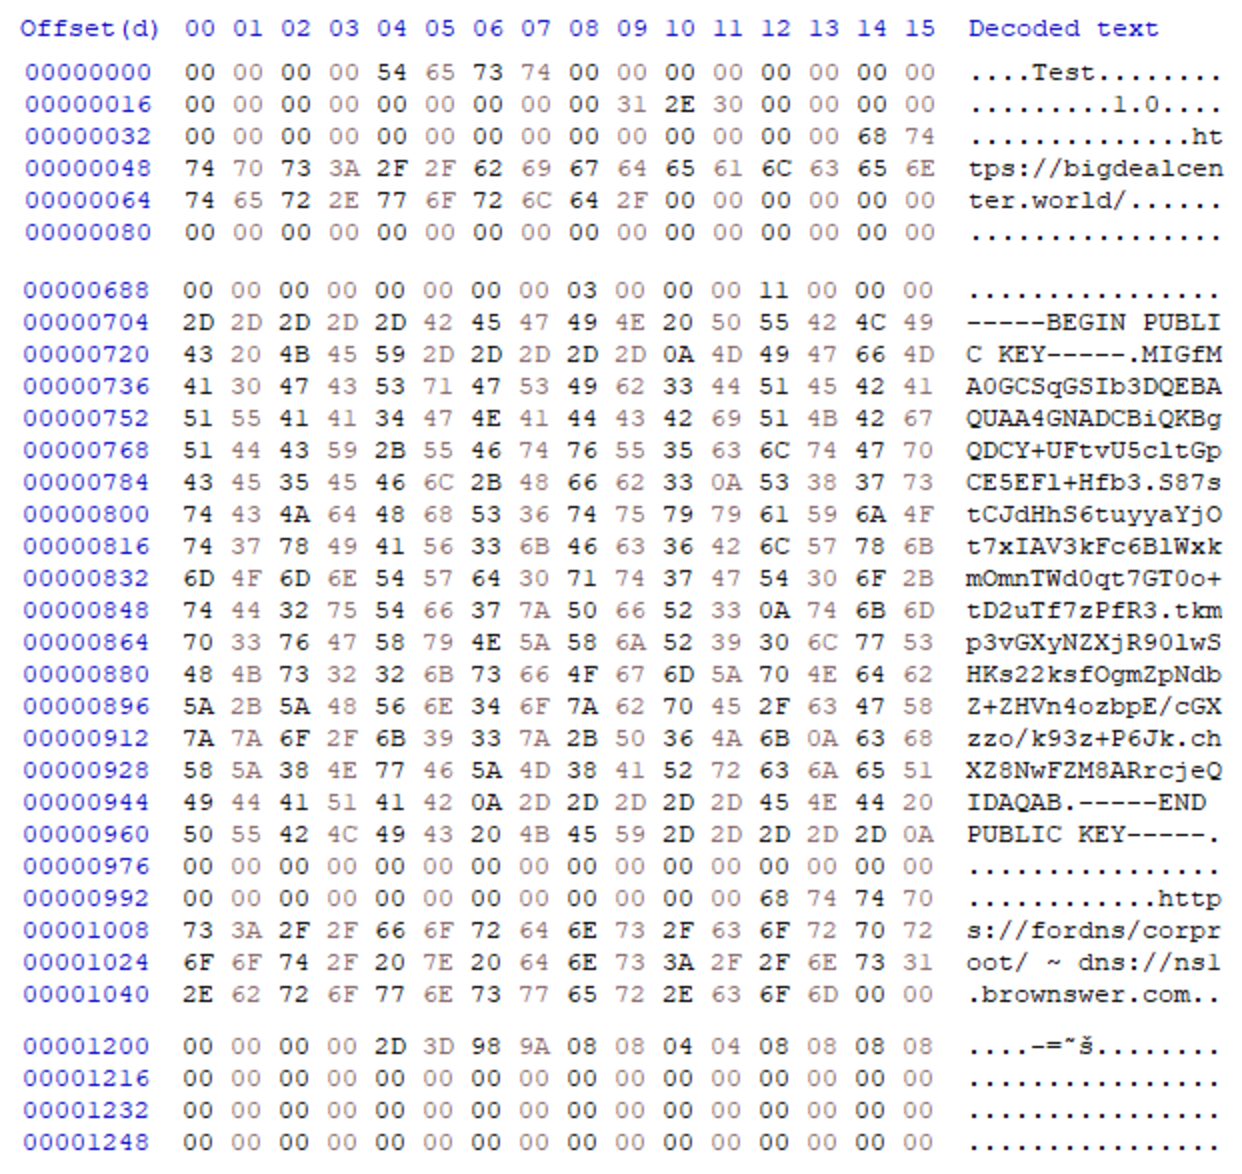
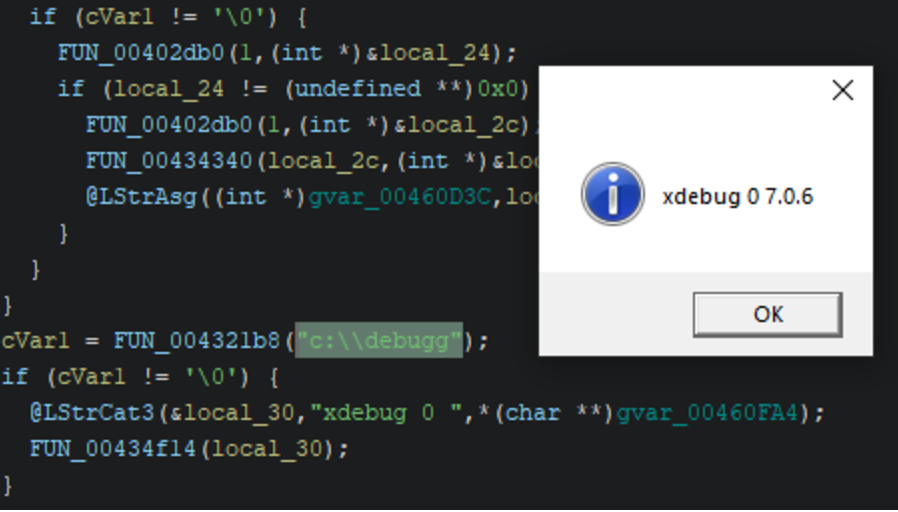
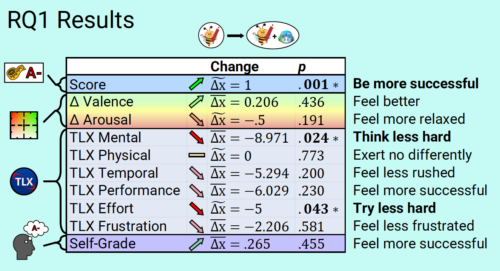
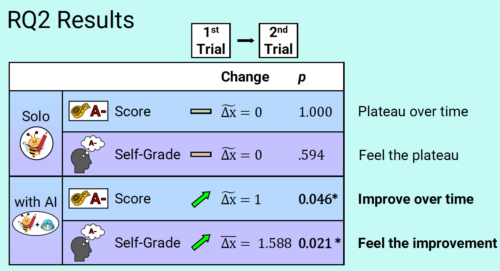



 Sotaro Hikita is an Analytics Solutions Architect. He supports customers across a wide range of industries in building and operating analytics platforms more effectively. He is particularly passionate about big data technologies and open source software.
 Noritaka Sekiyama is a Principal Big Data Architect on the AWS Glue team. He works based in Tokyo, Japan. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling with his road bike.
 Kyle Duong is a Senior Software Development Engineer on the AWS Glue and AWS Lake Formation team. He is passionate about building big data technologies and distributed systems.
 Sandeep Adwankar is a Senior Product Manager at AWS. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that enable customers to improve how they manage, secure, and access data.


