Tag Archives: AWS Key Management Service*

Round 2 post-quantum TLS is now supported in AWS KMS

Post Syndicated from Alex Weibel original https://aws.amazon.com/blogs/security/round-2-post-quantum-tls-is-now-supported-in-aws-kms/

AWS Key Management Service (AWS KMS) now supports three new hybrid post-quantum key exchange algorithms for the Transport Layer Security (TLS) 1.2 encryption protocol that’s used when connecting to AWS KMS API endpoints. These new hybrid post-quantum algorithms combine the proven security of a classical key exchange with the potential quantum-safe properties of new post-quantum key exchanges undergoing evaluation for standardization. The fastest of these algorithms adds approximately 0.3 milliseconds of overheard compared to a classical TLS handshake. The new post-quantum key exchange algorithms added are Round 2 versions of Kyber, Bit Flipping Key Encapsulation (BIKE), and Supersingular Isogeny Key Encapsulation (SIKE). Each organization has submitted their algorithms to the National Institute of Standards and Technology (NIST) as part of NIST’s post-quantum cryptography standardization process. This process spans several rounds of evaluation over multiple years, and is likely to continue beyond 2021.

In our previous hybrid post-quantum TLS blog post, we announced that AWS KMS had launched hybrid post-quantum TLS 1.2 with Round 1 versions of BIKE and SIKE. The Round 1 post-quantum algorithms are still supported by AWS KMS, but at a lower priority than the Round 2 algorithms. You can choose to upgrade your client to enable negotiation of Round 2 algorithms.

Why post-quantum TLS is important

A large-scale quantum computer would be able to break the current public-key cryptography that’s used for key exchange in classical TLS connections. While a large-scale quantum computer isn’t available today, it’s still important to think about and plan for your long-term security needs. TLS traffic using classical algorithms recorded today could be decrypted by a large-scale quantum computer in the future. If you’re developing applications that rely on the long-term confidentiality of data passed over a TLS connection, you should consider a plan to migrate to post-quantum cryptography before the lifespan of the sensitivity of your data would be susceptible to an unauthorized user with a large-scale quantum computer. As an example, this means that if you believe that a large-scale quantum computer is 25 years away, and your data must be secure for 20 years, you should migrate to post-quantum schemes within the next 5 years. AWS is working to prepare for this future, and we want you to be prepared too.

We’re offering this feature now instead of waiting for standardization efforts to be complete so you have a way to measure the potential performance impact to your applications. Offering this feature now also gives you the protection afforded by the proposed post-quantum schemes today. While we believe that the use of this feature raises the already high security bar for connecting to AWS KMS endpoints, these new cipher suites will impact bandwidth utilization and latency. However, using these new algorithms could also create connection failures for intermediate systems that proxy TLS connections. We’d like to get feedback from you on the effectiveness of our implementation or any issues found so we can improve it over time.

Hybrid post-quantum TLS 1.2

Hybrid post-quantum TLS is a feature that provides the security protections of both the classical and post-quantum key exchange algorithms in a single TLS handshake. Figure 1 shows the differences in the connection secret derivation process between classical and hybrid post-quantum TLS 1.2. Hybrid post-quantum TLS 1.2 has three major differences from classical TLS 1.2:

  • The negotiated post-quantum key is appended to the ECDHE key before being used as the hash-based message authentication code (HMAC) key.
  • The text hybrid in its ASCII representation is prepended to the beginning of the HMAC message.
  • The entire client key exchange message from the TLS handshake is appended to the end of the HMAC message.
Figure 1: Differences in the connection secret derivation process between classical and hybrid post-quantum TLS 1.2

Figure 1: Differences in the connection secret derivation process between classical and hybrid post-quantum TLS 1.2

Some background on post-quantum TLS

Today, all requests to AWS KMS use TLS with key exchange algorithms that provide perfect forward secrecy and use one of the following classical schemes:

While existing FFDHE and ECDHE schemes use perfect forward secrecy to protect against the compromise of the server’s long-term secret key, these schemes don’t protect against large-scale quantum computers. In the future, a sufficiently capable large-scale quantum computer could run Shor’s Algorithm to recover the TLS session key of a recorded classical session, and thereby gain access to the data inside. Using a post-quantum key exchange algorithm during the TLS handshake protects against attacks from a large-scale quantum computer.

The possibility of large-scale quantum computing has spurred the development of new quantum-resistant cryptographic algorithms. NIST has started the process of standardizing post-quantum key encapsulation mechanisms (KEMs). A KEM is a type of key exchange that’s used to establish a shared symmetric key. AWS has chosen three NIST KEM submissions to adopt in our post-quantum efforts:

Hybrid mode ensures that the negotiated key is as strong as the weakest key agreement scheme. If one of the schemes is broken, the communications remain confidential. The Internet Engineering Task Force (IETF) Hybrid Post-Quantum Key Encapsulation Methods for Transport Layer Security 1.2 draft describes how to combine post-quantum KEMs with ECDHE to create new cipher suites for TLS 1.2.

These cipher suites use a hybrid key exchange that performs two independent key exchanges during the TLS handshake. The key exchange then cryptographically combines the keys from each into a single TLS session key. This strategy combines the proven security of a classical key exchange with the potential quantum-safe properties of new post-quantum key exchanges being analyzed by NIST.

The effect of hybrid post-quantum TLS on performance

Post-quantum cipher suites have a different performance profile and bandwidth usage from traditional cipher suites. AWS has measured bandwidth and latency across 2,000 TLS handshakes between an Amazon Elastic Compute Cloud (Amazon EC2) C5n.4xlarge client and the public AWS KMS endpoint, which were both in the us-west-2 Region. Your own performance characteristics might differ, and will depend on your environment, including your:

  • Hardware–CPU speed and number of cores.
  • Existing workloads–how often you call AWS KMS and what other work your application performs.
  • Network–location and capacity.

The following graphs and table show latency measurements performed by AWS for all newly supported Round 2 post-quantum algorithms, in addition to the classical ECDHE key exchange algorithm currently used by most customers.

Figure 2 shows the latency differences of all hybrid post-quantum algorithms compared with classical ECDHE alone, and shows that compared to ECDHE alone, SIKE adds approximately 101 milliseconds of overhead, BIKE adds approximately 9.5 milliseconds of overhead, and Kyber adds approximately 0.3 milliseconds of overhead.
 

Figure 2: TLS handshake latency at varying percentiles for four key exchange algorithms

Figure 2: TLS handshake latency at varying percentiles for four key exchange algorithms

Figure 3 shows the latency differences between ECDHE with Kyber, and ECDHE alone. The addition of Kyber adds approximately 0.3 milliseconds of overhead.
 

Figure 3: TLS handshake latency at varying percentiles, with only top two performing key exchange algorithms

Figure 3: TLS handshake latency at varying percentiles, with only top two performing key exchange algorithms

The following table shows the total amount of data (in bytes) needed to complete the TLS handshake for each cipher suite, the average latency, and latency at varying percentiles. All measurements were gathered from 2,000 TLS handshakes. The time was measured on the client from the start of the handshake until the handshake was completed, and includes all network transfer time. All connections used RSA authentication with a 2048-bit key, and ECDHE used the secp256r1 curve. All hybrid post-quantum tests used the NIST Round 2 versions. The Kyber test used the Kyber-512 parameter, the BIKE test used the BIKE-1 Level 1 parameter, and the SIKE test used the SIKEp434 parameter.

Item Bandwidth
(bytes)
Total
handshakes
Average
(ms)
p0
(ms)
p50
(ms)
p90
(ms)
p99
(ms)
ECDHE (classic) 3,574 2,000 3.08 2.07 3.02 3.95 4.71
ECDHE + Kyber R2 5,898 2,000 3.36 2.38 3.17 4.28 5.35
ECDHE + BIKE R2 12,456 2,000 14.91 11.59 14.16 18.27 23.58
ECDHE + SIKE R2 4,628 2,000 112.40 103.22 108.87 126.80 146.56

By default, the AWS SDK client performs a TLS handshake once to set up a new TLS connection, and then reuses that TLS connection for multiple requests. This means that the increased cost of a hybrid post-quantum TLS handshake is amortized over multiple requests sent over the TLS connection. You should take the amortization into account when evaluating the overall additional cost of using post-quantum algorithms; otherwise performance data could be skewed.

AWS KMS has chosen Kyber Round 2 to be KMS’s highest prioritized post-quantum algorithm, with BIKE Round 2, and SIKE Round 2 next in priority order for post-quantum algorithms. This is because Kyber’s performance is closest to the classical ECDHE performance that most AWS KMS customers are using today and are accustomed to.

How to use hybrid post-quantum cipher suites

To use the post-quantum cipher suites with AWS KMS, you need the preview release of the AWS Common Runtime (CRT) HTTP client for the AWS SDK for Java 2.x. Also, you will need to configure the AWS CRT HTTP client to use the s2n post-quantum hybrid cipher suites. Post-quantum TLS for AWS KMS is available in all AWS Regions except for AWS GovCloud (US-East), AWS GovCloud (US-West), AWS China (Beijing) Region operated by Beijing Sinnet Technology Co. Ltd (“Sinnet”), and AWS China (Ningxia) Region operated by Ningxia Western Cloud Data Technology Co. Ltd. (“NWCD”). Since NIST has not yet standardized post-quantum cryptography, connections that require Federal Information Processing Standards (FIPS) compliance cannot use the hybrid key exchange. For example, kms.<region>.amazonaws.com supports the use of post-quantum cipher suites, while kms-fips.<region>.amazonaws.com does not.

  1. If you’re using the AWS SDK for Java 2.x, you must add the preview release of the AWS Common Runtime client to your Maven dependencies.
    <dependency>
        <groupId>software.amazon.awssdk</groupId>
        <artifactId>aws-crt-client</artifactId>
        <version>2.14.13-PREVIEW</version>
    </dependency>
    

  2. You then must configure the new SDK and cipher suite in the existing initialization code of your application:
    if(!TLS_CIPHER_PREF_KMS_PQ_TLSv1_0_2020_07.isSupported()){
        throw new RuntimeException("Post Quantum Ciphers not supported on this Platform");
    }
    
    SdkAsyncHttpClient awsCrtHttpClient = AwsCrtAsyncHttpClient.builder()
              .tlsCipherPreference(TLS_CIPHER_PREF_KMS_PQ_TLSv1_0_2020_07)
              .build();
              
    KmsAsyncClient kms = KmsAsyncClient.builder()
             .httpClient(awsCrtHttpClient)
             .build();
             
    ListKeysResponse response = kms.listKeys().get();
    

Now, all connections made to AWS KMS in supported Regions will use the new hybrid post-quantum cipher suites! To see a complete example of everything set up, check out the example application here.

Things to try

Here are some ideas about how to use this post-quantum-enabled client:

  • Run load tests and benchmarks. These new cipher suites perform differently than traditional key exchange algorithms. You might need to adjust your connection timeouts to allow for the longer handshake times or, if you’re running inside an AWS Lambda function, extend the execution timeout setting.
  • Try connecting from different locations. Depending on the network path your request takes, you might discover that intermediate hosts, proxies, or firewalls with deep packet inspection (DPI) block the request. This could be due to the new cipher suites in the ClientHello or the larger key exchange messages. If this is the case, you might need to work with your security team or IT administrators to update the relevant configuration to unblock the new TLS cipher suites. We’d like to hear from you about how your infrastructure interacts with this new variant of TLS traffic. If you have questions or feedback, please start a new thread on the AWS KMS discussion forum.

Conclusion

In this blog post, I announced support for Round 2 hybrid post-quantum algorithms in AWS KMS, and showed you how to begin experimenting with hybrid post-quantum key exchange algorithms for TLS when connecting to AWS KMS endpoints.

More info

If you’d like to learn more about post-quantum cryptography check out:

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
Author

Alex Weibel

Alex is a Senior Software Engineer on the AWS Crypto Algorithms team. He’s one of the maintainers for Amazon’s TLS Library s2n. Previously, Alex worked on TLS termination and request proxying for S3 and the Elastic Load Balancing Service developing new features for customers. Alex holds a Bachelor of Science degree in Computer Science from the University of Texas at Austin.

Combining encryption and signing with AWS asymmetric keys

Post Syndicated from J.D. Bean original https://aws.amazon.com/blogs/security/combining-encryption-and-signing-with-aws-asymmetric-keys/

In this post, I discuss how to use AWS Key Management Service (KMS) to combine asymmetric digital signature and asymmetric encryption of the same data.

The addition of support for asymmetric keys in AWS KMS has exciting use cases for customers. The ability to create, manage, and use public and private key pairs with KMS enables you to perform digital signing operations using RSA and Elliptic Curve Cryptography (ECC) keys. AWS KMS asymmetric keys can also be used to perform digital encryption operations using RSA keys. You can use these features together to digitally sign and encrypt the same data.

Another notable property of AWS KMS asymmetric keys is that they enable disconnected use cases. For example AWS KMS asymmetric keys can be used to cryptographically verify a digital signature client-side without the need for a network connection. AWS KMS asymmetric keys also enable scenarios where customers can use KMS to securely manage decryption of data that has been encrypted by a partner’s system that does not integrate with AWS APIs or have access to AWS account credentials. For the sake of simplicity, however, the example that I discuss in this post describes a connected use case where all cryptographic actions are performed server-side in AWS KMS using AWS credentials. The use of AWS KMS asymmetric keys throughout this post allows the overall approach to be adapted to disconnected and/or non-AWS-integrated use cases.

Overview

This post contains three basic steps.

  1. Create and configure AWS asymmetric customer master keys (CMK), AWS Identity and Access Management (IAM) roles, and key policies.
  2. Use your asymmetric CMKs to encrypt and sign a sample message in the role of a sender.
  3. Use AWS KMS to decrypt and verify the message signature of the sample message archive you generated in the previous procedure using your asymmetric CMKs in the role of a receiver.

Prerequisites

The commands I use in this tutorial were tested using AWS Command Line Interface (AWS CLI) version 2.50 on Amazon Linux 2. In order to run these commands in your in your own local environment ensure that you have first installed and updated the AWS CLI.

I assume you have at least one administrator identity available to you that has broad rights for creating roles, assuming roles, as well as creating, managing and using KMS keys. This can be a federated identity (for example, from your corporate identity provider or from a social identity), or it can be an AWS IAM user. Where no AWS identity is mentioned, I assume that you will be accessing the AWS Management Console or the AWS CLI using this administrator identity.

For simplicity, I create the KMS keys in the same region as each other. You must specify an AWS Region when using the AWS CLI, either explicitly or by setting a default Region. Before beginning, you should select an AWS Region to work in such as US East (N. Virginia). If you have not configured the AWS CLI in your environment please review the Configuration basics section of the AWS Command Line Interface User Guide for instructions. You may revert this configuration once you have finished if you do not wish to continue using a default Region with your AWS CLI. Take note of your selected region. When working in the AWS Console, if you do not see resources, such as AWS KMS keys, that you expect you may want to confirm that you are viewing resources in your chosen Region. For more information on selecting your Region in the AWS Console see Choosing a Region in AWS Management Console Getting Started Guide.

Create and configure resources

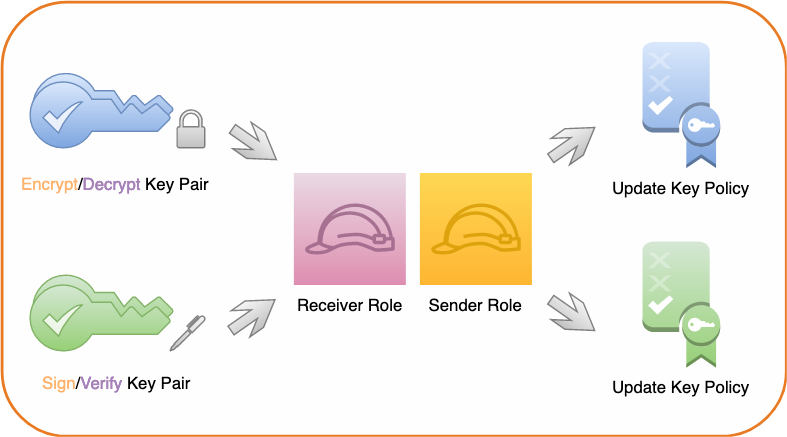
In the first phase of this tutorial you create and configure two asymmetric AWS KMS CMKs, two AWS IAM roles, and configure the key policies for both of your KMS CMKs to grant permissions to the roles. Shown in the following figure.
 

Figure 1: Create keys, roles, and key policies

Figure 1: Create keys, roles, and key policies

Create asymmetric signing and encryption key pairs

In the first step, you create two asymmetric master keys (CMK). One is configured for signing and verifying digital signatures while the other is configured for encrypting and decrypting data.

Note: The CMKs configured for this post are examples. RSA and Elliptic curve CMKs key specs can differ in a variety of dimensions. The RSA or elliptic curve key spec that you choose might be determined by your security standards or the requirements of your task. Different CMK key specs are priced differently and are subject to different request quotas because they each have different performance profiles. In general, use RSA or ECC keys with the highest security level that is practical and affordable for your task. For more information on CMK configuration options, please review the How to choose your CMK configuration section of the KMS Developer Guide.

To create a CMK for encryption and decryption

  1. Use the KMS CreateKey API. Pass RSA_4096 for the CustomerMasterKeySpec parameter and ENCRYPT_DECRYPT for the KeyUsage parameter in the AWS CLI example command below in order to generate a RSA 4096 key pair for signature creation and verification using AWS KMS.
    aws kms create-key --customer-master-key-spec RSA_4096 \
        --key-usage ENCRYPT_DECRYPT \
        --description "Sample Digital Encryption Key Pair"
    

    Note: If successful, this command returns a KeyMetadata object. Take note of the KeyID value in this object.

  2. As a best practice, assign an alias for your key. Use the following command to assign an alias of sample-encrypt-decrypt-key to your newly created CMK (replace the target-key-id value of 1234abcd-12ab-34cd-56ef-1234567890ab with your KeyID). Mapping a human-readable alias to the KeyID will make it easier to identify, use, and manage.
    aws kms create-alias \
        --alias-name alias/sample-encrypt-decrypt-key \
        --target-key-id 1234abcd-12ab-34cd-56ef-1234567890ab
    

To create a CMK for signature and verification

  1. Use the KMS CreateKey API. Pass ECC_NIST_P521 for the CustomerMasterKeySpec parameter and SIGN_VERIFY for the KeyUsage parameter in the AWS CLI example command below in order to generate an elliptic curve (ECC) key pair for signature creation and verification using AWS KMS.
    aws kms create-key --customer-master-key-spec \
        ECC_NIST_P521  \
        --key-usage SIGN_VERIFY \
        --description "Sample Digital Signature Key Pair"
    

    Note: If successful, this command returns a KeyMetadata object. Take note of the KeyID value.

  2. Use the following command to assign an alias of sample-sign-verify-key to your newly created CMK (replace the target-key-id value of 1234abcd-12ab-34cd-56ef-1234567890ab with your KeyID).
    aws kms create-alias \
        --alias-name alias/sample-sign-verify-key \
        --target-key-id 1234abcd-12ab-34cd-56ef-1234567890ab
    

Create sender and receiver roles

For the next step of this tutorial, you create two AWS principals. Use the steps that follow to create two roles—a sender principal and a receiver principal. Later, you will grant permissions to perform private key operations (sign and decrypt) and public key operations (verify and encrypt) to these roles.

To create and configure the roles

  1. Navigate to the AWS Identity and Access Management (IAM) Create role console dialogue that allows entities in a specified account to assume the role. Enter your Account ID and choose Next, as shown in the following figure.

    Note: If you don’t know you AWS account ID, please read Finding you AWS account ID in the AWS IAM User Guide for guidance on how to obtain this information.

    Figure 2: Enter your account ID to begin creating a role in AWS IAM

    Figure 2: Enter your account ID to begin creating a role in AWS IAM

  2. Select Next through the next two screens.

    Note: By clicking next through these dialogues you do not attach an IAM permissions policy or a tag to this new role.

  3. On the final screen, enter a Role name of SenderRole and a Role description of your choice, as shown in the following figure.
     
    Figure 3: Create the sender role

    Figure 3: Create the sender role

  4. Choose Create role to finish creating the sender role.
  5. To create the receiver role, repeat the preceding role creation process. However, in step 3, substitute the name ReceiverRole for SenderRole.

Configure key policy permissions

Best practice is to adhere to the principle of least privilege and provide each AWS principal with the minimal permissions necessary to perform its tasks. The sender and receiver roles that you created in the previous step currently have no permissions in your account. For this scenario, the receiver principal must be granted permission to verify digital signatures and decrypt data in AWS KMS using your asymmetric CMKs and the sender principal must be granted permission to create digital signatures and encrypt data in KMS using your asymmetric CMKs.

To provide access control permissions for AWS KMS actions to your AWS principals, attach a key policy to each of your CMKs.

Modify the CMK key policy

For the sample-encrypt-decrypt-key CMK, grant the IAM role for the sender principal (SenderRole) kms:Encrypt permissions and the IAM role for the receiver principal (ReceiverRole) kms:Decrypt permissions in the CMK key policy.

To modify the CMK key policy (console)

  1. Navigate to the AWS KMS page in the AWS Console and select customer-managed keys.
  2. Select your sample-encrypt-decrypt-key CMK.
  3. In the key policy section, choose edit.
  4. To allow your receiver principal to use the CMK to decrypt data encrypted under that CMK, append the following statement to the key policy (replace the account ID value of 111122223333 with your own).
    {
        "Sid": "Allow use of the CMK for decryption",
        "Effect": "Allow",
        "Principal": {"AWS":"arn:aws:iam::111122223333:role/ReceiverRole"},
        "Action": "kms:Decrypt",
        "Resource": "*"
    }
    

  5. To allow your sender principal to use the CMK to encrypt data, append the following statement to the key policy (replace the account ID value of 111122223333 with your own):
    {
        "Sid": "Allow use of the CMK for encryption",
        "Effect": "Allow",
        "Principal": {"AWS":"arn:aws:iam::111122223333:role/SenderRole"},
        "Action": "kms:Encrypt",
        "Resource": "*"
    }
    

  6. Choose Save changes.

Note: The kms:Encrypt permission is sufficient to permit the sender principal to encrypt small amounts of arbitrary data using your CMK directly.

Grant sign and verify permissions to the CMK key policy

For the sample-sign-verify-key CMK, grant the IAM role for the sender principal (SenderRole) kms:Sign permissions in the CMK key policy and the IAM role for the receiver principal (ReceiverRole) kms:Verify permissions in the CMK key policy.

To grant sign and verify permissions

  1. Using the same process as above, navigate to the key policy edit dialog for the sample-sign-verify-key CMK in the AWS console.
  2. To allow your sender principal to use the CMK to create digital signatures, append the following statement to the key policy (replace the account ID value of 111122223333 with your own).
    {
        "Sid": "Allow use of the CMK for digital signing",
        "Effect": "Allow",
        "Principal": {"AWS":"arn:aws:iam::111122223333:role/SenderRole"},
        "Action": "kms:Sign",
        "Resource": "*"
    }
    

  3. To allow your receiver principal to use the CMK to verify signatures created by that CMK, append the following statement to the key policy (replace the account ID value of 111122223333 with your own):
    {
        "Sid": "Allow use of the CMK for digital signature verification",
        "Effect": "Allow",
        "Principal": {"AWS":"arn:aws:iam::111122223333:role/ReceiverRole"},
        "Action": "kms:Verify",
        "Resource": "*"
    }
    

  4. Choose Save changes.

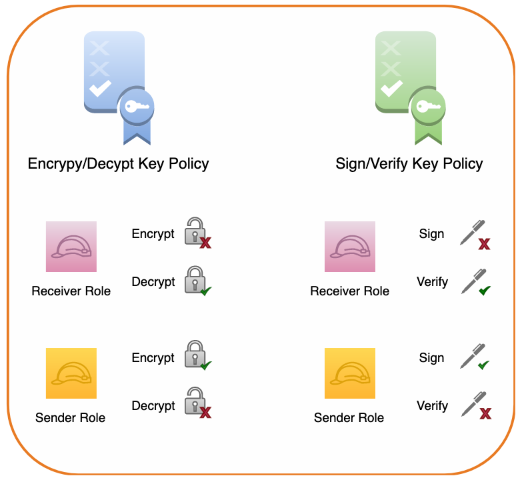
Key permissions summary

When these key policy edits have been completed the sender principal:

  • Will have permissions to encrypt data using the sample-encrypt-decrypt-key CMK and generate digital signatures using the sample-sign-verify-key CMK.
  • Will not have permissions to decrypt or to verify signatures using the CMKs.

The receiver principal:

  • Will have permissions to decrypt data which has been encrypted using the sample-encrypt-decrypt-key CMK and to verify signatures created using the sample-sign-verify-key CMK.
  • Will not have permissions to encrypt or to generate signatures using the CMKs.
Figure 4: Summary of key policy permissions

Figure 4: Summary of key policy permissions

Signing and encrypting a sample message

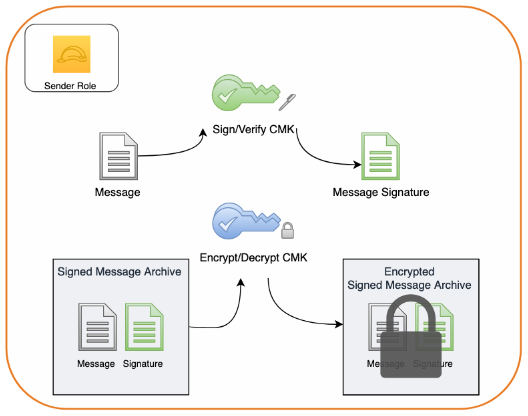
So far, you’ve created two asymmetric CMKs, created a set of sender and receiver roles, and configured permissions for those roles in each of your CMK key policies. In the second phase of this tutorial, you assume the role of sender and use your asymmetric signature and verification CMK to sign a sample message. You then bundle the sample message and its corresponding digital signature together into an archive and use your encryption and decryption asymmetric CMK to encrypt the archive.
 

Figure 5: Creating a message signature and encrypting the message along with its signature

Figure 5: Creating a message signature and encrypting the message along with its signature

Note: The order of operations in this process is that the message is first signed and then the signature and the message are encrypted together. This order is intentional. When a message is signed and then encrypted, neither the contents nor the identity of the sender will be available to unauthorized 3rd parties. If the order of operations were reversed, however, and a message was first encrypted and then signed it could leak information about the sender’s identity to unauthorized 3rd parties. Moreover, when a message is encrypted and then signed, an unauthorized 3rd party with access to the files could discard the authentic signature created by the sender and replace it with a valid signature created by their own key. This creates the potential for a 3rd party to deceptively create the appearance that they are the legitimate sender of the message and exploit that misperception further.

Assume the sender role

Start by assuming the sender role. In order to successfully assume a role you must authenticate as an IAM principal which has permission to perform sts:AssumeRole. If the principal you are authenticated as lacks this permission you will not able to assume the sender role.

To assume the sender role

  1. Run the following command, but be sure to replace the account ID value of 111122223333 with your account ID:
    aws sts assume-role \
        --role-arn arn:aws:iam::111122223333::role/SenderRole \
        --role-session-name AWSCLI-Session
    

  2. The return value for this command provides an access key ID, secret key, and session token. Substitute them into their respective places in the following commands and execute:
    export AWS_ACCESS_KEY_ID=ExampleAccessKeyID1
    export AWS_SECRET_ACCESS_KEY=ExampleSecretKey1
    export AWS_SESSION_TOKEN=ExampleSessionToken1
    

  3. Confirm that you’ve successfully assumed the sender role by issuing:
    aws sts get-caller-identity
    

    Note: If the output of this command contains the text assumed-role/SenderRole, then you’ve successfully assumed the sender role.

Create a message

Now, create a sample message file called message.json.

To create a message

Run the following command to create a message with the following content:

echo "
{ 
    "message": "The Magic Words are Squeamish Ossifrage", 
    "sender": "Sender Principal" 
}
" > ./message.json 

Create a digital signature

Creating and verifying a digital signature for the message provides confidence that the message contents haven’t been altered after being sent. This characteristic is known as integrity. Furthermore, when access to a signing key is scoped to a particular principal, creating and verifying a digital signature for the message provides confidence in the sender’s identity. This characteristic is known as authenticity. Finally, a high degree of confidence in both the integrity and authenticity of a message limits the plausible ability of a sender to fraudulently deny having signed a message. This characteristic is known a non-repudiation.

To create a digital signature

Run the following command to create a digital signature for message.json:

aws kms sign \
    --key-id alias/sample-sign-verify-key \
    --message-type RAW \
    --signing-algorithm ECDSA_SHA_512 \
    --message fileb://message.json \
    --output text \
    --query Signature | base64 --decode > message.sig

This generates an independent digital signature file, message.sig, for message.json. Any modification to the contents of message.json, such as changing the sender or message fields, will now cause signature validation of message.sig to fail for message.json.

Encrypt the message and signature

Even with the benefits of a digital signature, the message could still be viewed by any party with access to the file. In order to provide confidence that the message contents aren’t exposed to unauthorized parties, you can encrypt the message. This characteristic is known as confidentiality. In order to retain the benefits of your digital signature you can encrypt the message and corresponding signature together in a single package.

To encrypt the message and signature

  1. Combine your message and signature into an archive. For example, with the GNU Tar utility you can issue the following:
    tar -czvf message.tar.gz message.sig message.json
    

    This will create a new archive file named message.tar.gz containing both your message and message signature.

  2. Encrypt the archive using AWS KMS. To do so, issue the following command:
    aws kms encrypt \
        --key-id alias/sample-encrypt-decrypt-key \
        --encryption-algorithm RSAES_OAEP_SHA_256 \
        --plaintext fileb://message.tar.gz \
        --output text \
        --query CiphertextBlob | base64 --decode > message.enc
    

    This will output a message.enc file containing an encrypted copy of the message.tar.gz archive.

Decrypting and verifying a sample message

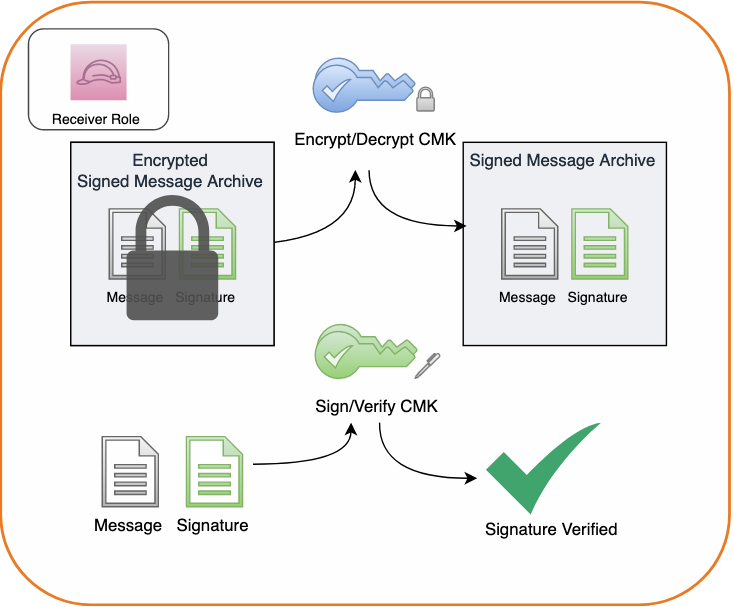
Now that you’ve created, signed, and encrypted a message, let’s change gears and see what working with this message.enc file is like from the perspective of a receiving party. In the final phase of this tutorial you assume the role of receiver and use your asymmetric CMKs to decrypt the encrypted message archive and verify the digital signature that you created. Finally, you will view your message. The process is shown in the following figure.
 

Figure 6: Decrypting a message archive and verifying the message signature

Figure 6: Decrypting a message archive and verifying the message signature

Assume the receiver role

Assume the receiver role so that you can simulate receiving a signed and encrypted message. As before, in order to assume the receiver role you must authenticate as an IAM principal which has permission to perform sts:AssumeRole. If the principal you are authenticated as lacks this permission you will not able to assume the receiver role.

To assume the receiver role

  1. Copy the message.enc file to a new directory to create a clean working space and navigate there in a terminal session.
  2. Assume your receiver role. To do so, execute the following command, replacing the account ID value of 111122223333 with your own:
    aws sts assume-role \
    	--role-arn arn:aws:iam::111122223333::role/ReceiverRole \
    	--role-session-name AWSCLI-Session
    

  3. The return value for this command provides an access key ID, secret key, and session token. Substitute them into their respective places in the following commands and execute:
    export AWS_ACCESS_KEY_ID=ExampleAccessKeyID1
    export AWS_SECRET_ACCESS_KEY=ExampleSecretKey1
    export AWS_SESSION_TOKEN=ExampleSessionToken1
    

  4. Confirm that you have successfully assumed the receiver role by issuing:
    aws sts get-caller-identity
    

If the output of this command contains the text assumed-role/ReceiverRole then you have successfully assumed the receiver role.

Decrypt the encrypted message archive in AWS KMS

Decrypt the encrypted message archive to access the plaintext of the message and message signature files.

To decrypt the encrypted message archive

  1. Issue the following command:
    aws kms decrypt \
        --key-id alias/sample-encrypt-decrypt-key \
        --ciphertext-blob fileb://EncryptedMessage \
        --encryption-algorithm RSAES_OAEP_SHA_256 \
        --output text \
        --query Plaintext | base64 --decode > message.tar.gz
    

  2. This will create an unencrypted message.tar.gz file that you can unpack with:
    tar -xvfz message.tar.gz
    

This, in turn, will expand the archive contents message.sig and message.json in your working directory.

Verify the message signature

To verify the signature on the message issue the following command:

aws kms verify \
    --key-id alias/sample-sign-verify-key \
    --message-type RAW \
    --message fileb://message.json \
    --signing-algorithm ECDSA_SHA_512 \
    --signature fileb://message.sig

In the response you should see that SignatureValid is marked true indicating that the signature has been verified using the specified sample-sign-verify-key that you granted the sender principal permission to generate signatures with.

View the message

Finally, open message.json and view the file’s contents by issuing the following command:

less message.json

You will see that the contents of the file have not been modified and still read:

{ 
    "message": "The Magic Words are Squeamish Ossifrage", 
    "sender": "Sender Principal" 
}

Note: Be careful to avoid making any changes to the contents of this file. Even a minor modification of the message contents will compromise the integrity of the message and cause future attempts at signature validation using your message.sig file to fail.

Summary

In this tutorial, you signed and encrypted data using two AWS KMS asymmetric CMKs and later decrypted and verified your signature using those CMKs.

You first created two asymmetric CMKs in AWS KMS, one for creating and verifying digital signatures and the other for encrypting and decrypting data. You then configured key policy permissions for your sender and receiver principals. Acting as your sender principal, you digitally signed a message in AWS KMS, added the message and signature to an archive and then encrypted that archive in AWS KMS. Next you assumed your receiver role and decrypted the archive in AWS KMS, viewed your message, and verified its signature in AWS KMS.

To learn more about the asymmetric keys feature of AWS KMS, please read the AWS KMS Developer Guide. If you have questions about the asymmetric keys feature, please start a new thread on the AWS KMS forum. If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

J.D. Bean

J.D. is a Senior Solutions Architect at AWS working with public sector organizations and financial institutions based out of New York City. His interests include security, privacy, and compliance. He is passionate about his work enabling AWS customers’ successful cloud journeys. J.D. holds a Bachelor of Arts from The George Washington University and a Juris Doctor from New York University School of Law.

Architecting a Data Lake for Higher Education Student Analytics

Post Syndicated from Craig Jordan original https://aws.amazon.com/blogs/architecture/architecting-data-lake-for-higher-education-student-analytics/

One of the keys to identifying timely and impactful actions is having enough raw material to work with. However, this up-to-date information typically lives in the databases that sit behind several different applications. One of the first steps to finding data-driven insights is gathering that information into a single store that an analyst can use without interfering with those applications.

For years, reporting environments have relied on a data warehouse stored in a single, separate relational database management system (RDBMS). But now, due to the growing use of Software as a service (SaaS) applications and NoSQL database options, data may be stored outside the data center and in formats other than tables of rows and columns. It’s increasingly difficult to access the data these applications maintain, and a data warehouse may not be flexible enough to house the gathered information.

For these reasons, reporting teams are building data lakes, and those responsible for using data analytics at universities and colleges are no different. However, it can be challenging to know exactly how to start building this expanded data repository so it can be ready to use quickly and still expandable as future requirements are uncovered. Helping higher education institutions address these challenges is the topic of this post.

About Maryville University

Maryville University is a nationally recognized private institution located in St. Louis, Missouri, and was recently named the second fastest growing private university by The Chronicle of Higher Education. Even with its enrollment growth, the university is committed to a highly personalized education for each student, which requires reliable data that is readily available to multiple departments. University leaders want to offer the right help at the right time to students who may be having difficulty completing the first semester of their course of study. To get started, the data experts in the Office of Strategic Information and members of the IT Department needed to create a data environment to identify students needing assistance.

Critical data sources

Like most universities, Maryville’s student-related data centers around two significant sources: the student information system (SIS), which houses student profiles, course completion, and financial aid information; and the learning management system (LMS) in which students review course materials, complete assignments, and engage in online discussions with faculty and fellow students.

The first of these, the SIS, stores its data in an on-premises relational database, and for several years, a significant subset of its contents had been incorporated into the university’s data warehouse. The LMS, however, contains data that the team had not tried to bring into their data warehouse. Moreover, that data is managed by a SaaS application from Instructure, called “Canvas,” and is not directly accessible for traditional extract, transform, and load (ETL) processing. The team recognized they needed a new approach and began down the path of creating a data lake in AWS to support their analysis goals.

Getting started on the data lake

The first step the team took in building their data lake made use of an open source solution that Harvard’s IT department developed. The solution, comprised of AWS Lambda functions and Amazon Simple Storage Service (S3) buckets, is deployed using AWS CloudFormation. It enables any university that uses Canvas for their LMS to implement a solution that moves LMS data into an S3 data lake on a daily basis. The following diagram illustrates this portion of Maryville’s data lake architecture:

The data lake for the Learning Management System data

Diagram 1: The data lake for the Learning Management System data

The AWS Lambda functions invoke the LMS REST API on a daily schedule resulting in Maryville’s data, which has been previously unloaded and compressed by Canvas, to be securely stored into S3 objects. AWS Glue tables are defined to provide access to these S3 objects. Amazon Simple Notification Service (SNS) informs stakeholders the status of the data loads.

Expanding the data lake

The next step was deciding how to copy the SIS data into S3. The team decided to use the AWS Database Migration Service (DMS) to create daily snapshots of more than 2,500 tables from this database. DMS uses a source endpoint for secure access to the on-premises database instance over VPN. A target endpoint determines the specific S3 bucket into which the data should be written. A migration task defines which tables to copy from the source database along with other migration options. Finally, a replication instance, a fully managed virtual machine, runs the migration task to copy the data. With this configuration in place, the data lake architecture for SIS data looks like this:

Diagram 2: Migrating data from the Student Information System

Diagram 2: Migrating data from the Student Information System

Handling sensitive data

In building a data lake you have several options for handling sensitive data including:

  • Leaving it behind in the source system and avoid copying it through the data replication process
  • Copying it into the data lake, but taking precautions to ensure that access to it is limited to authorized staff
  • Copying it into the data lake, but applying processes to eliminate, mask, or otherwise obfuscate the data before it is made accessible to analysts and data scientists

The Maryville team decided to take the first of these approaches. Building the data lake gave them a natural opportunity to assess where this data was stored in the source system and then make changes to the source database itself to limit the number of highly sensitive data fields.

Validating the data lake

With these steps completed, the team turned to the final task, which was to validate the data lake. For this process they chose to make use of Amazon Athena, AWS Glue, and Amazon Redshift. AWS Glue provided multiple capabilities including metadata extraction, ETL, and data orchestration. Metadata extraction, completed by Glue crawlers, quickly converted the information that DMS wrote to S3 into metadata defined in the Glue data catalog. This enabled the data in S3 to be accessed using standard SQL statements interactively in Athena. Without the added cost and complexity of a database, Maryville’s data analyst was able to confirm that the data loads were completing successfully. He was also able to resolve specific issues encountered on particular tables. The SQL queries, written in Athena, could later be converted to ETL jobs in AWS Glue, where they could be triggered on a schedule to create additional data in S3. Athena and Glue enabled the ETL that was needed to transform the raw data delivered to S3 into prepared datasets necessary for existing dashboards.

Once curated datasets were created and stored in S3, the data was loaded into an AWS Redshift data warehouse, which supported direct access by tools outside of AWS using ODBC/JDBC drivers. This capability enabled Maryville’s team to further validate the data by attaching the data in Redshift to existing dashboards that were running in Maryville’s own data center. Redshift’s stored procedure language allowed the team to port some key ETL logic so that the engineering of these datasets could follow a process similar to approaches used in Maryville’s on-premises data warehouse environment.

Conclusion

The overall data lake/data warehouse architecture that the Maryville team constructed currently looks like this:

The complete architecture

Diagram 3: The complete architecture

Through this approach, Maryville’s two-person team has moved key data into position for use in a variety of workloads. The data in S3 is now readily accessible for ad hoc interactive SQL workloads in Athena, ETL jobs in Glue, and ultimately for machine learning workloads running in EC2, Lambda or Amazon Sagemaker. In addition, the S3 storage layer is easy to expand without interrupting prior workloads. At the time of this writing, the Maryville team is both beginning to use this environment for machine learning models described earlier as well as adding other data sources into the S3 layer.

Acknowledgements

The solution described in this post resulted from the collaborative effort of Christine McQuie, Data Engineer, and Josh Tepen, Cloud Engineer, at Maryville University, with guidance from Travis Berkley and Craig Jordan, AWS Solutions Architects.

Architecting for database encryption on AWS

Post Syndicated from Jonathan Jenkyn original https://aws.amazon.com/blogs/security/architecting-for-database-encryption-on-aws/

In this post, I review the options you have to protect your customer data when migrating or building new databases in Amazon Web Services (AWS). I focus on how you can support sensitive workloads in ways that help you maintain compliance and regulatory obligations, and meet security objectives.

Understanding transparent data encryption

I commonly see enterprise customers migrating existing databases straight from on-premises to AWS without reviewing their design. This might seem simpler and faster, but they miss the opportunity to review the scalability, cost-savings, and feature capability of native cloud services. A straight lift and shift migration can also create unnecessary operational overheads, carry-over unneeded complexity, and result in more time spent troubleshooting and responding to events over time.

One example is when enterprise customers who are using Transparent Data Encryption (TDE) or Extensible Key Management (EKM) technologies want to reuse the same technologies in their migration to AWS. TDE and EKM are database technologies that encrypt and decrypt database records as the records are written and read to the underlying storage medium. Customers use TDE features in Microsoft SQL Server, Oracle 10g and 11g, and Oracle Enterprise Edition to meet requirements for data-at-rest encryption. This shouldn’t mean that TDE is the requirement. It’s infrequent that an organizational policy or compliance framework specifies a technology such as TDE in the actual requirement. For example, the Payment Card Industry Data Security Standard (PCI-DSS) standard requires that sensitive data must be protected using “Strong cryptography with associated key-management processes and procedures.” Nowhere does PCI-DSS endorse or require the use of a specific technology.

Understanding risks

It’s important that you understand the risks that encryption-at-rest mitigates before selecting a technology to use. Encryption-at-rest, in the context of databases, generally manages the risk that one of the disks used to store database data is physically stolen and thus compromised. In on-premises scenarios, TDE is an effective technology used to manage this risk. All data from the database—up to and including the disk—is encrypted. The database manages all key management and cryptographic operations. You can also use TDE with a hardware security module (HSM) so that the keys and cryptography for the database are managed outside of the database itself. In TDE implementations, the HSM is used only to manage the key encryption keys (KEK), and not the data encryption keys (DEK) themselves. The DEKs are in volatile memory in the database at runtime, and so the cryptographic operations occur on the database itself.

You can also use native operating system encryption technologies such as dm-crypt or LUKS (Linux Unified Key Setup). Dm-crypt is a full disk encryption (FDE) subsystem in Linux kernel version 2.6 and beyond. Dm-crypt can be used on its own or with LUKS as an extension to add more features. When using dm-crypt, the operating system kernel is responsible for encrypting and decrypting data as it’s written and read from the attached volumes. This would achieve the same outcome as TDE—data written and read to the disk volume is encrypted, and the risk related to physical disk compromise is managed. DEKs are in runtime memory of the machine running the database.

With some TDE implementations, you can encrypt tables, rows, columns, and cells with different DEKs to achieve granular separation of duties between operators. Customers can then configure TDE to authorize access to each DEK based on database login credentials and job function, helping to manage risks associated with unauthorized access. However, the most common configuration I’ve seen is to rely on whole database encryption when using TDE. This configuration gives similar protection against the identified risks as dm-crypt with LUKS used without an HSM, since the DEKs and KEKs are stored within the instance in both cases and the result is that the database data on disk is encrypted.

Using encryption to manage data at rest risks in AWS

When you move to AWS, you gain additional security capabilities that can simplify your security implementations. Since the announcement of the AWS Key Management Service (AWS KMS) in 2014, it has been tightly integrated with Amazon Elastic Block Store (Amazon EBS), Amazon Simple Storage Service (Amazon S3), and dozens of other services on AWS. This means that data is encrypted on disk by checking a single check box. Furthermore, you get the benefits of AWS KMS for key management and cryptographic operations, while being transparent to the Amazon Elastic Compute Cloud (Amazon EC2) instance where the data is being encrypted and decrypted. For simplicity, the authorization for access to the data is managed entirely by AWS Identity and Access Management (IAM) and AWS KMS key resource policies.

If you need more granular access control to the data, you can use the AWS Encryption SDK to encrypt data at the application layer. That provides the same effect as TDE cell-level protection, with a FIPS140-2 Level 2 validated HSM, as might be required by a recognizing standard.

If you must use a FIPS140-2 Level 3 validated HSM to meet more stringent compliance standards or regulations, then you can use the Custom Key Store capability of AWS KMS to achieve that—again in a transparent way. This option has a trade-off, as there is additional operational overhead in terms of managing an AWS CloudHSM cluster.

Many customers choose to migrate their database into the managed Amazon Relational Database Service (Amazon RDS), rather than managing the database instance themselves. Like the Amazon EC2 service, RDS uses Amazon EBS volumes for its data storage, and so can seamlessly use AWS KMS for encryption at rest functionality. When you do so, your management overhead for the protection of data-at-rest reduces to almost zero. This lets you focus on business value while AWS is responsible for the management of your database and the protection of the underlying data. The next section reviews this option and others in more detail.

You can review the available Amazon RDS database engines and versions via the Amazon RDS User Guide documentation, or by running the following AWS Command Line Interface (AWS CLI) command:

aws rds describe-db-engine-versions --query "DBEngineVersions[].DBEngineVersionDescription" --region <regionIdentifier>

Recommended Solutions

If you’re moving an existing database to AWS, you have the following solutions for data at rest encryption. I go into more detail for each option below.

Table 1 – Encryption options

Option Database management Host Encryption Key management
1 Amazon managed Amazon RDS Amazon EBS AWS KMS
2 Amazon managed Amazon RDS Amazon EBS AWS KMS Custom Key Store
3 Customer managed Amazon EC2 Amazon EBS AWS KMS
4 Customer managed Amazon EC2 Amazon EBS AWS KMS Custom Key Store
5 Customer managed Amazon EC2 Amazon EBS LUKS
6 Customer managed Amazon EC2 Database Database TDE
7 Customer managed Amazon EC2 Database CloudHSM

Option 1 – Using Amazon RDS with Amazon EBS encryption and key management provided by AWS KMS

This approach uses the Amazon RDS service where AWS manages the operating system and database engine. You can configure this service to be a highly scalable resource spanning multiple Availability Zones within an AWS Region to provide resiliency. AWS KMS manages the keys that are used to encrypt the attached Amazon EBS volumes at rest.

Note: This configuration is recommended as your default database encryption approach.

Benefits

  • No key management requirement on host; key management is automated and performed by AWS KMS
  • Meets FIPS140-2 Level 2 validation requirements
  • Simple vertical and horizontal scalability
  • Snapshots for recovery are encrypted automatically
  • AWS manages the patching, maintenance, and configuration of the operating system and database engine
  • Well-recognized configuration, with support offered through AWS Support
  • AWS KMS costs are comparatively low

Challenges

  • Dependent on Amazon RDS supported engines and versions
  • Might require additional controls to manage unauthorized access at table, row, column, or cell level

Option 2 – Using Amazon RDS with Amazon EBS encryption and key management provided by AWS KMS custom key store

This approach uses the Amazon RDS service where AWS manages the operating system and database engine. You can configure this service to be a highly scalable resource spanning multiple Availability Zones within a Region to provide resiliency. CloudHSM keys are used via AWS KMS service integration to encrypt the Amazon EBS volumes at rest.

Note: This configuration is recommended where FIPS140-2 Level 3 validation is a specified compliance requirement.

Benefits

  • No key management requirement on host; key management is performed by AWS KMS
  • Meets FIPS140-2 Level 3 validation requirements
  • Simple vertical and horizontal scalability
  • Snapshots for recovery are encrypted automatically
  • AWS manages the patching, maintenance, and configuration of the database engine
  • Well-recognized configuration with support offered through AWS Support

Challenges

  • Dependent on Amazon RDS supported engines and versions
  • You are responsible for provisioning, configuration, scaling, maintenance, and costs of running CloudHSM cluster
  • Might require additional controls to manage unauthorized access at table, row, column or cell level

Option 3 – Customer-managed database platform hosted on Amazon EC2 with Amazon EBS encryption and key management provided by KMS

In this approach, the key difference is that you’re responsible for managing the EC2 instances, operating systems, and database engines. You can still configure your databases to be highly scalable resources spanning multiple Availability Zones within a Region to provide resiliency, but it takes more effort. AWS KMS manages the keys that are used to encrypt the attached Amazon EBS volumes at rest.

Note: This configuration is recommended when Amazon RDS doesn’t support the desired database engine type or version.

Benefits

  • A 1:1 relationship for migration of database engine configuration
  • Key rotation and management is handled transparently by AWS
  • Data encryption keys are managed by the hypervisor, not by your EC2 instance
  • AWS KMS costs are comparatively low

Challenges

  • You’re responsible for patching and updates of the database engine and OS
  • Might require additional controls to manage unauthorized access at table, row, column, or cell level

Option 4 – Customer-managed database platform hosted on Amazon EC2 with Amazon EBS encryption and key management provided by KMS custom key store

In this approach, you are again responsible for managing the EC2 instances, operating systems, and database engines. You can still configure your databases to be highly scalable resources spanning multiple Availability Zones within a Region to provide resiliency, but it takes more effort. And similar to Option 2, CloudHSM keys are used via AWS KMS service integration to encrypt the Amazon EBS volumes at rest.

Note: This configuration is recommended when Amazon RDS doesn’t support the desired database engine type or version and when FIPS140-2 Level 3 compliance is required.

Benefits

  • A 1:1 relationship for migration of database engine configuration
  • Data encryption keys managed by the hypervisor, not by your EC2 instance
  • Keys managed by FIPS140-2 Level 3 validated HSM

Challenges

  • You’re responsible for provisioning, configuration, scaling, maintenance, and costs of running CloudHSM cluster
  • You’re responsible for patching and updates of the database engine and OS
  • Might require additional controls to manage unauthorized access at table, row, column, or cell level

Option 5 – Customer-managed database platform hosted on Amazon EC2 with Amazon EBS encryption and key management provided by LUKS

In this approach, you’re still responsible for managing the EC2 instances, operating systems, and database engines. You also need to install LUKS onto the Linux instance to manage the encryption of data on Amazon EBS.

Benefits

  • A 1:1 relationship for migration of database engine configuration
  • Transparent encryption is managed by OS with LUKS

Challenges

  • You’re responsible for patching and updates of the database engine and OS
  • Data encryption keys are managed directly on the EC2 instance, and not a dedicated key management system
  • Scaling must be vertical, which is slow and costly
  • LUKS is supported through open-source licensing
  • Support for backup and recovery is LUKS specific, and require additional consideration
  • Might require additional controls to manage unauthorized access at table, row, column or cell level

Note: This approach limits you to only Linux instances and requires the most technical knowledge and effort on your part. Options, such as BitLocker and SQL Server Always Encrypted, exist for Windows hosts, and the complexity and challenges are similar to those of LUKS.

Option 6 – Customer-managed database platform hosted on Amazon EC2 with database encryption and key management provided by TDE

In this approach, you’re still responsible for managing the EC2 instances, operating systems, and database engines. However, instead of encrypting the Amazon EBS volume where the database is stored, you use TDE wallet keys managed by the database engine to encrypt and decrypt records as they are stored and retrieved.

Benefits

  • A 1:1 relationship for migration of database engine configuration
  • Table, row, column, and cell level encryption are managed by TDE, reducing end point risks relating to unauthorized access

Challenges

  • You’re responsible for patching and updates of the database engine and OS
  • Costly license for TDE feature
  • Data encryption keys are managed directly on the EC2 instance
  • Scaling is dependent on TDE functionality and Amazon EC2 scaling
  • Support is split between AWS and a third-party database vendor
  • Cannot share snapshots

Note: This approach is not available with Amazon RDS.

Option 7 – Customer-managed database platform hosted on Amazon EC2 with database encryption performed by TDE and key management provided by CloudHSM

In this approach, you’re still responsible for managing the EC2 instances, operating systems, and database engines. However, instead of encrypting the Amazon EBS volume where the database is stored, you use TDE wallet keys managed by a CloudHSM cluster to encrypt and decrypt records as they are stored and retrieved.

Benefits

  • A 1:1 relationship for migration of database engine configuration
  • Wallet keys (KEK) are managed by a FIPS140-2 Level 3 validated HSM
  • Table, row, column, and cell level encryption are managed by TDE, reducing end point risks relating to unauthorized access

Challenges

  • You’re responsible for patching and updates of the database engine and OS
  • Costly license for TDE feature
  • You are responsible for provisioning, configuration, scaling, maintenance, and costs of running CloudHSM cluster
  • Integration and support of CloudHSM with TDE might vary
  • Scaling is dependent on TDE functionality, Amazon EC2 scaling, and CloudHSM cluster.
  • Data encryption keys are managed on EC2 instance
  • Support is split between AWS and a third-party database vendor
  • Cannot share snapshots

Note: This approach is not available with Amazon RDS.

Summary

While you can operate in AWS similar to how you operate in your on-premises environment, the preceding configurations and recommendations show how you can significantly reduce your challenges and increase your benefits by using cloud-native security services like AWS KMS, Amazon RDS, and CloudHSM. Specifically, using Amazon RDS with Amazon EBS volumes encrypted by AWS KMS provides a highly scalable, resilient, and secure way to manage your keys in AWS.

While there might be some architectural redesign and configuration work needed to move an on-premises database into Amazon RDS, you can leverage AWS services to help you meet your compliance requirements with less effort. By offloading the OS and database maintenance responsibility to AWS, you simultaneously reduce operational friction and increase security. By migrating this way, you can benefit from the scalability and resilience of the AWS global infrastructure and expertise. Lastly, to get started with migrating your database to AWS, I encourage you to use the AWS Database Migration Service.

If you have feedback about this post, submit comments in the Comments section below.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Jonathan Jenkyn

Jonathan is a Senior Security Growth Strategies Consultant with AWS Professional Services. He’s an active member of the People with Disabilities affinity group, and has built several Amazon initiatives supporting charities and social responsibility causes. Since 1998, he has been involved in IT Security at many levels, from implementation of cryptographic primitives to managing enterprise security governance. Outside of work, he enjoys running, cycling, fund-raising for the BHF and Ipswich Hospital Charity, and spending time with his wife and 5 children.

Author

Scott Conklin

Scott is a Senior Security Consultant with AWS Professional Services (Global Specialty Practice). Based out of Chicago with 4 years tenure, he is an avid distance runner, crypto nerd, lover of unicorns, and enjoys camping, nature, playing Minecraft with his 3 kids, and binge watching Amazon Prime with his wife.

Improved client-side encryption: Explicit KeyIds and key commitment

Post Syndicated from Alex Tribble original https://aws.amazon.com/blogs/security/improved-client-side-encryption-explicit-keyids-and-key-commitment/

I’m excited to announce the launch of two new features in the AWS Encryption SDK (ESDK): local KeyId filtering and key commitment. These features each enhance security for our customers, acting as additional layers of protection for your most critical data. In this post I’ll tell you how they work. Let’s dig in.

The ESDK is a client-side encryption library designed to make it easy for you to implement client-side encryption in your application using industry standards and best practices. Since the security of your encryption is only as strong as the security of your key management, the ESDK integrates with the AWS Key Management Service (AWS KMS), though the ESDK doesn’t require you to use any particular source of keys. When using AWS KMS, the ESDK wraps data keys to one or more customer master keys (CMKs) stored in AWS KMS on encrypt, and calls AWS KMS again on decrypt to unwrap the keys.

It’s important to use only CMKs you trust. If you encrypt to an untrusted CMK, someone with access to the message and that CMK could decrypt your message. It’s equally important to only use trusted CMKs on decrypt! Decrypting with an untrusted CMK could expose you to ciphertext substitution, where you could decrypt a message that was valid, but written by an untrusted actor. There are several controls you can use to prevent this. I recommend a belt-and-suspenders approach. (Technically, this post’s approach is more like a belt, suspenders, and an extra pair of pants.)

The first two controls aren’t new, but they’re important to consider. First, you should configure your application with an AWS Identity and Access Management (IAM) policy that only allows it to use specific CMKs. An IAM policy allowing Decrypt on “Resource”:”*” might be appropriate for a development or testing account, but production accounts should list out CMKs explicitly. Take a look at our best practices for IAM policies for use with AWS KMS for more detailed guidance. Using IAM policy to control access to specific CMKs is a powerful control, because you can programmatically audit that the policy is being used across all of your accounts. To help with this, AWS Config has added new rules and AWS Security Hub added new controls to detect existing IAM policies that might allow broader use of CMKs than you intended. We recommend that you enable Security Hub’s Foundational Security Best Practices standard in all of your accounts and regions. This standard includes a set of vetted automated security checks that can help you assess your security posture across your AWS environment. To help you when writing new policies, the IAM policy visual editor in the AWS Management Console warns you if you are about to create a new policy that would add the “Resource”:”*” condition in any policy.

The second control to consider is to make sure you’re passing the KeyId parameter to AWS KMS on Decrypt and ReEncrypt requests. KeyId is optional for symmetric CMKs on these requests, since the ciphertext blob that the Encrypt request returns includes the KeyId as metadata embedded in the blob. That’s quite useful—it’s easier to use, and means you can’t (permanently) lose track of the KeyId without also losing the ciphertext. That’s an important concern for data that you need to access over long periods of time. Data stores that would otherwise include the ciphertext and KeyId as separate objects get re-architected over time and the mapping between the two objects might be lost. If you explicitly pass the KeyId in a decrypt operation, AWS KMS will only use that KeyId to decrypt, and you won’t be surprised by using an untrusted CMK. As a best practice, pass KeyId whenever you know it. ESDK messages always include the KeyId; as part of this release, the ESDK will now always pass KeyId when making AWS KMS Decrypt requests.

A third control to protect you from using an unexpected CMK is called local KeyId filtering. If you explicitly pass the KeyId of an untrusted CMK, you would still be open to ciphertext substitution—so you need to be sure you’re only passing KeyIds that you trust. The ESDK will now filter KeyIds locally by using a list of trusted CMKs or AWS account IDs you configure. This enforcement happens client-side, before calling AWS KMS. Let’s walk through a code sample. I’ll use Java here, but this feature is available in all of the supported languages of the ESDK.

Let’s say your app is decrypting ESDK messages read out of an Amazon Simple Queue Service (Amazon SQS) queue. Somewhere you’ll likely have a function like this:

public byte[] decryptMessage(final byte[] messageBytes,
                             final Map<String, String> encryptionContext) {
    // The Amazon Resource Name (ARN) of your CMK.
    final String keyArn = "arn:aws:kms:us-west-2:111122223333:key/1234abcd-12ab-34cd-56ef-1234567890ab";

    // 1. Instantiate the SDK
    AwsCrypto crypto = AwsCrypto.builder().build();

Now, when you create a KmsMasterKeyProvider, you’ll configure it with one or more KeyIds you expect to use. I’m passing a single element here for simplicity.

	// 2. Instantiate a KMS master key provider in Strict Mode using buildStrict()
    final KmsMasterKeyProvider keyProvider = KmsMasterKeyProvider.builder().buildStrict(keyArn); 

Decrypt the message as normal. The ESDK will check each encrypted data key against the list of KeyIds configured at creation: in the preceeding example, the single CMK in keyArn. The ESDK will only call AWS KMS for matching encrypted data keys; if none match, it will throw a CannotUnwrapDataKeyException.

	// 3. Decrypt the message.
    final CryptoResult<byte[], KmsMasterKey> decryptResult = crypto.decryptData(keyProvider, messageBytes);

    // 4. Validate the encryption context.
    //

(See our documentation for more information on how encryption context provides additional authentication features!)

	checkEncryptionContext(decryptResult, encryptionContext);

    // 5. Return the decrypted bytes.
    return decryptResult.getResult();
}

We recommend that everyone using the ESDK with AWS KMS adopt local KeyId filtering. How you do this varies by language—the ESDK Developer Guide provides detailed instructions and example code.

I’m especially excited to announce the second new feature of the ESDK, key commitment, which addresses a non-obvious property of modern symmetric ciphers used in the industry (including the Advanced Encryption Standard (AES)). These ciphers have the property that decrypting a single ciphertext with two different keys could give different plaintexts! Picking a pair of keys that decrypt to two specific messages involves trying random keys until you get the message you want, making it too expensive for most messages. However, if you’re encrypting messages of a few bytes, it might be feasible. Most authenticated encryption schemes, such as AES-GCM, don’t solve for this issue. Instead, they prevent someone who doesn’t control the keys from tampering with the ciphertext. But someone who controls both keys can craft a ciphertext that will properly authenticate under each key by using AES-GCM.

All of this means that if a sender can get two parties to use different keys, those two parties could decrypt the exact same ciphertext and get different results. That could be problematic if the message reads, for example, as “sell 1000 shares” to one party, and “buy 1000 shares” to another.

The ESDK solves this problem for you with key commitment. Key commitment means that only a single data key can decrypt a given message, and that trying to use any other data key will result in a failed authentication check and a failure to decrypt. This property allows for senders and recipients of encrypted messages to know that everyone will see the same plaintext message after decryption.

Key commitment is on by default in version 2.0 of the ESDK. This is a breaking change from earlier versions. Existing customers should follow the ESDK migration guide for their language to upgrade from 1.x versions of the ESDK currently in their environment. I recommend a thoughtful and careful migration.

AWS is always looking for feedback on ways to improve our services and tools. Security-related concerns can be reported to AWS Security at [email protected]. We’re deeply grateful for security research, and we’d like to thank Thai Duong from Google’s security team for reaching out to us. I’d also like to thank my colleagues on the AWS Crypto Tools team for their collaboration, dedication, and commitment (pun intended) to continuously improving our libraries.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Crypto Tools forum or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.
Author

Alex Tribble

Alex is a Principal Software Development Engineer in AWS Crypto Tools. She joined Amazon in 2008 and has spent her time building security platforms, protecting availability, and generally making things faster and cheaper. Outside of work, she, her wife, and children love to pack as much stuff into as few bikes as possible.