Post-quantum cryptography is now one pip-install away for the entire Python ecosystem. With funding from the Sovereign Tech Agency, we implemented support for ML-KEM, the NIST-standard key-establishment primitive, and ML-DSA, the NIST-standard digital-signature primitive, in pyca/cryptography.
Remember, the reason to do this now is because there’s no emergency. And because you will make your systems crypto agile, which is always a good idea.
Abstract: This Article updates and expands on 2012 research on encryption and globalization, analyzing what the authors call “Round 3” of the Going Dark Debate: the current controversies over end-to-end encryption (E2EE). Governments around the world have proposed, and in some cases enacted, laws limiting E2EE for law enforcement and national security purposes.
This Article explains the underlying technologies and market developments for a law and policy audience to assess those proposals critically. The Article proceeds in three parts tracking three rounds of the Going Dark Debate. Round 1 covers the Crypto Wars of the 1990s, when U.S. export controls on strong encryption ultimately fell in 1999. Round 2 covers the period roughly 2010 to 2015, when encryption-in-transit became widespread but lawful access remained available through cloud providers, giving rise to what the authors called a “golden age of surveillance” rather than a period of going dark. Round 3 addresses the current debate over E2EE, where no entity between sender and recipient can read the plaintext.
The Article’s first major contribution is identifying five technically distinct scenarios for how E2EE operates in practice, each with different implications for lawful access. These scenarios reveal a substantial gap between the assumption that E2EE categorically blocks lawful access and the reality of how communications are sent and received. Second, the Article shows that E2EE is not limited to messaging; instead, it is embedded throughout the modern technology stack, including in Transport Layer Security, Secure Shell, Virtual Private Networks, and Zero Trust Architecture, the last of which is now legally required under U.S. and EU law. Any law broadly limiting E2EE would thus have severe serious consequences for cybersecurity, commerce, and government operations. The Article concludes that the two key lessons from Round 2—the least trusted country problem and the golden age of surveillance—remain true in Round 3, and that new government claims for restricting effective encryption deserve great skepticism.
Really interesting piece of cryptographic history:
In November 2023, a large cache of his wartime papers—nicknamed the “Bayley papers”—was auctioned in London for almost half a million U.S. dollars. The previously unknown cache contains many sheets in Turing’s own handwriting, telling of his top-secret “Delilah” engineering project from 1943 to 1945. Delilah was Turing’s portable voice-encryption system, named after the biblical deceiver of men. There is also material written by Bayley, often in the form of notes he took while Turing was speaking. It is thanks to Bayley that the papers survived: He kept them until he died in 2020, 66 years after Turing passed away.
France is accelerating its transition to post-quantum encryption:
France’s cybersecurity agency ANSSI said on Tuesday it would stop certifying security products that lack quantum-resistant encryption, a move that will force government bodies and critical operators to shift away from older systems.
Samih Souissi, ANSSI’s chief of staff, said at the France Quantum conference that the agency would halt such certifications from 2027, and that businesses should be buying only quantum-safe products by 2030.
ANSSI approval is required for use in French government agencies and critical infrastructure, making the policy a de facto phase-out of older encryption.
Interesting research on a new class of weak RSA keys: keys with lots of zeros. It turns out that these keys are out in the wild.
The badkeys project is an open-source service that checks public keys for known vulnerabilities. While developing this tool, Hanno collected a massive number of real-world keys from public sources, including Certificate Transparency logs, internet-wide TLS and SSH scans, PGP keys, and many others. By searching this dataset for unexpectedly sparse RSA moduli, we uncovered a large number of keys in the wild with the patterns in Figure 1.
Both patterns include several regularly spaced blocks of all zeros interleaved with seemingly random data. Pattern 1 appears in CT logs for certificates issued to several large organizations, including Yahoo and Verizon, and on some devices running NetApp software. Fortunately, these certificates have already expired, but we still shared our findings with these companies. We wanted to learn more about which product could be responsible for generating these keys, but we did not hear back. Pattern 2 appears on SSH hosts running the CompleteFTP software from EnterpriseDT. The underlying vulnerability affects RSA keys generated using versions 10.0.012.0.0 (Dec 2016Mar 2019) and DSA keys generated with v10.0.023.0.4 (Dec 2016Dec 2023).
These vulnerabilities affect a small minority of hosts on the internet, but the more interesting takeaway is that independent cryptographic implementations failed in similar ways. More implementations may include the same bugs, and so it’s worth tailoring cryptanalytic algorithms for this particular type of failure.
The article doesn’t speculate, but I will. This could be a deliberately designed backdoor, of the sort I wrote about back in 2013. I could imagine some government agency figuring out how to break this class of RSA keys, and then convincing different providers to hand them out to users.
Migrating your TLS endpoints to Post-quantum cryptography (PQC) starts with understanding your current TLS endpoint inventory and posture. This post introduces the PQC Readiness Scanner — an automated tool that inventories your Application Load Balancer (ALB), Network Load Balancer (NLB), and Amazon API Gateway endpoints and continuously monitors their TLS configurations for PQC readiness. The scanner classifies each endpoint into a three-tier framework that helps prioritize and plan PQC migration.
As quantum computing advances, you need to migrate to quantum-resistant cryptography to protect your data long-term. The PQC Readiness Scanner helps you identify which endpoints to migrate first and tracks your progress across accounts. For web traffic, PQC key exchange algorithms are negotiated only within TLS 1.3. This means quantum-resistant connections require endpoints that support TLS 1.3 and PQC key exchange.
Under the AWS Shared Responsibility Model, AWS secures the infrastructure and enables PQC support across its services. Customers are responsible for configuring their resources to use PQC-capable TLS policies. For AWS-terminated TLS connections—such as those on Application Load Balancer (ALB),Network Load Balancer (NLB), Amazon API Gateway, and Amazon CloudFront—customers choose the security policy (an AWS-managed configuration defining supported TLS protocol versions and cipher suites for a listener) that determines TLS version and cipher suite, key exchange, and authentication algorithm support.
The automated PQC Readiness Scanner for AWS-terminated TLS endpoints is built using AWS Config conformance packs. A conformance pack is a collection of AWS Config rules and remediation actions that can be deployed as a single entity in an account and a Region or across an organization in AWS Organizations.
Solution overview
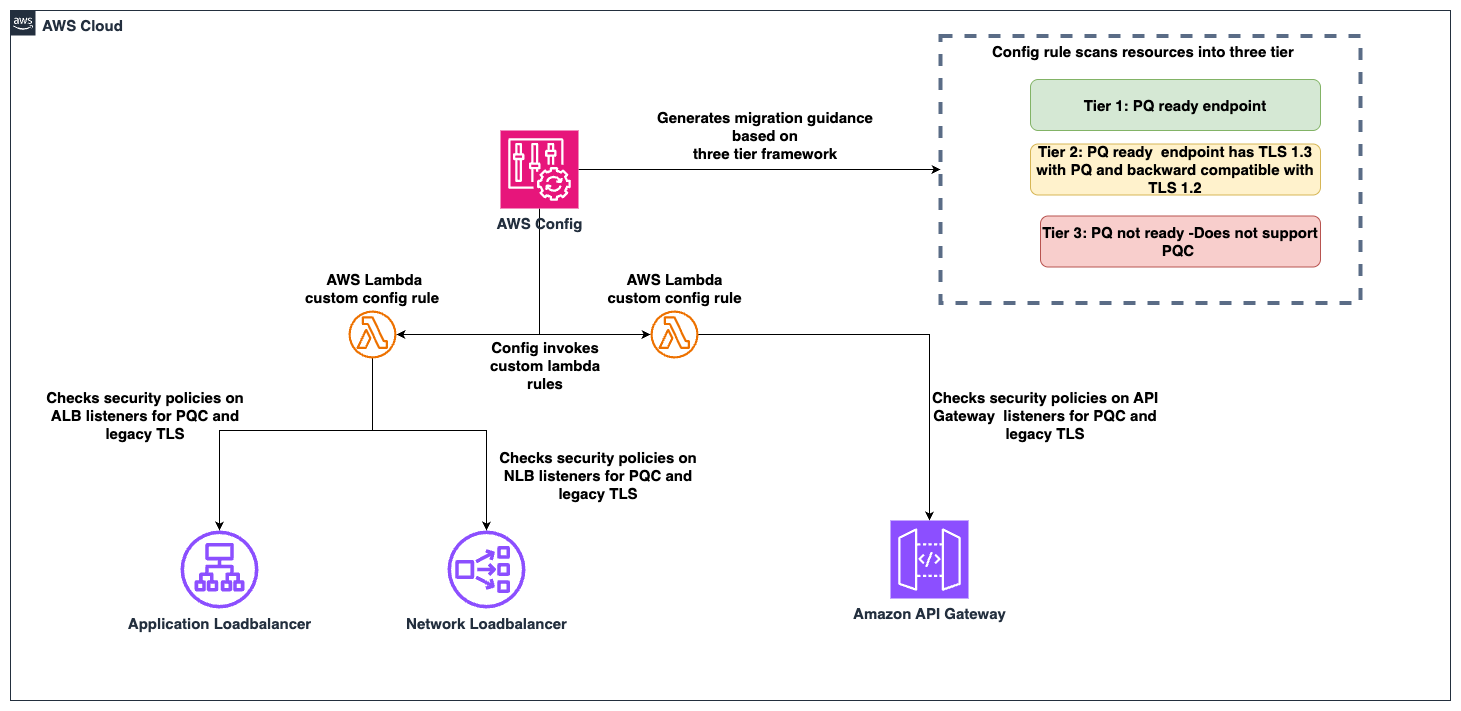
The PQC Readiness Scanner deploys AWS Config rules using a conformance pack to evaluate the security policy on each endpoint. Based on the evaluation, each resource is classified into a three-tier readiness framework that prioritizes migration actions needed to achieve PQ-ready TLS.
The PQC Readiness Scanner performs two checks per resource:
Does the endpoint use a PQ-ready security policy?
Does the endpoint support legacy TLS 1.0 or 1.1?
Each check returns COMPLIANT or NON_COMPLIANT status with specific policy recommendations.
PQC requires endpoints to support TLS 1.3 and use PQC key exchange algorithms. The three-tier framework helps you interpret findings and prioritize fixes. The goal is to have TLS 1.3 with PQC key exchange enabled on the endpoints. However, achieving this requires maintaining backward compatibility with clients.
Tier
Readiness level
TLS protocols
PQC status
Migration priority
Tier 1
PQ-ready (strongest posture)
TLS 1.3 only with PQC key exchange
PQ-ready
None
Tier 2
PQ-ready (backward compatible)
TLS 1.2 and 1.3 with PQC key exchange
PQ-ready
Low
Tier 3
Not PQ-ready
No PQC key exchange
Not PQ-ready
High
How to prioritize your migrations
Tier 1 represents the strongest security using only TLS 1.3 with PQC key exchange. These resources already meet the target state.
Tier 2 represents a backward-compatible PQ-ready configuration. Endpoints support both TLS 1.2 and TLS 1.3, with PQC key exchange negotiated on TLS 1.3 connections. Migration priority is low because these resources already provide quantum-resistant protection for clients that support TLS 1.3, while maintaining TLS 1.2 compatibility for legacy clients. Migrate to Tier 1 when client-side analysis confirms that the connecting clients support TLS 1.3 with PQC key exchange.
Tier 3 covers resources that aren’t PQ-ready. This includes endpoints without TLS 1.3 support, endpoints with TLS 1.3 but without PQC key exchange policies. These resources require immediate attention.
Assessment scope
The scanner evaluates the following AWS edge services that terminate TLS connections on behalf of your applications.
Edge services:
Application Load Balancer (ALB), Network Load Balancer (NLB) listeners with HTTPS, TLS, and TCP SSL protocols are evaluated.
API Gateway REST APIs are evaluated for AWS Regional and private endpoints along with API Gateway HTTP APIs (v2) and WebSocket APIs (v2).
Excluded edge services:
CloudFront distributions are excluded from the PQC readiness scope because TLS 1.3 with hybrid post-quantum key exchange is automatically enabled across existing CloudFront TLS security policies for viewer-to-edge connections. No customer action is required for inbound (viewer-facing) PQC on CloudFront.
Recommended approach for Classic load balancer:
For Classic Load Balancers, AWS recommends migrating to ALB or NLB. Classic Load Balancers don’t support TLS 1.3 or PQC key exchange and can’t be made PQ-ready.
How the solution works
AWS Config enables continuous monitoring and evaluation. Conformance packs enable organization-wide deployment. AWS Lambda is a serverless compute service that runs code to perform security policy evaluation based on the AWS Config rules. AWS Serverless Application Model (AWS SAM) is an open source framework used for deploying the AWS Lambda functions.
Figure 1: PQC readiness solution architecture
The PQC Readiness Scanner conformance pack implements four custom AWS Config rules powered by two Lambda functions:
Rule
What it checks
Non-compliant result
ELB PQ-ready
Load balancer listeners use security policies that support TLS 1.3 with PQC key exchange algorithms
Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy
ELB legacy TLS
Load balancer listeners allow TLS 1.0 or 1.1 connections
Legacy protocols are configured, the resource is flagged.
API Gateway PQ-ready
API Gateway endpoints use security policies that support TLS 1.3 with PQC key exchange algorithms
Policy doesn’t include PQC support, the resource is marked with a recommended upgrade policy
API Gateway legacy TLS
API Gateway endpoints allow TLS 1.0 or 1.1
Legacy protocols are configured, the resource is flagged.
Deploy the PQC Readiness Config Scanner in three phases. Complete deployment commands and configuration details are available in the GitHub repository. The Lambda functions must be deployed first because the conformance pack references their ARNs as parameters. See the GitHub repository for details.
Deploy to single account:
Clone and Build:
git clone https://github.com/aws-samples/sample-PQC-Readiness-using-AWS-Config.git

cd sample-PQC-Readiness-using-AWS-Config/installation

sam build
Deploy to One or More Regions:
# Make script executable (first time only)
chmod +x deploy-per-regions.sh

# Deploy to a single region
./deploy-per-regions.sh us-east-1

# Deploy to multiple regions
./deploy-per-regions.sh us-east-1 us-west-2 eu-west-1
Figure 2: Type y and continue if you have enabled AWS Config recording for these resources or its by default recording all resources.
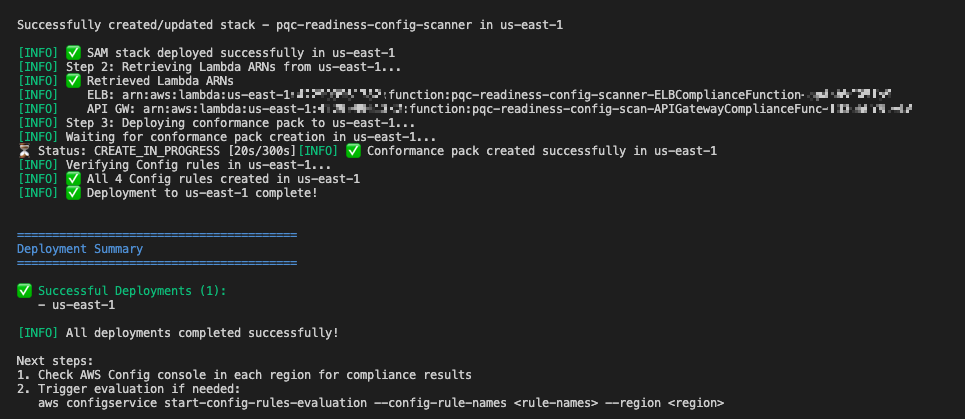
The script automatically:
Deploys Lambda functions via SAM
Deploys conformance pack (creates Config rules)
Verifies deployment success
Provides clear status messages
The deployment creates two Lambda functions that perform PQ-ready and legacy TLS checks. It provisions IAM roles with least-privilege permissions for ELB, ALB, NLB, and API Gateway describe operations. Lambda permissions allow AWS Config to invoke the functions.
Figure 3: Example screen-print of what a successful deployment looks like.
Multi-account deployment (Organizations):
For organization-wide deployment across multiple AWS accounts, use CloudFormation StackSets to deploy Lambda functions to each account.
Important Constraint: AWS Config CUSTOM_LAMBDA rules require the Lambda function to exist in the same account as the Config rule. You cannot use a centralized Lambda in one account to evaluate resources in other accounts.
Prerequisite: Shared S3 Bucket
Before packaging, create an S3 bucket accessible by each target account in your organization. This bucket will host the Lambda deployment artifacts that CloudFormation StackSets pulls into each member account.
# Create the shared S3 bucket (run from management/central account)
aws s3 mb s3://<your-org-shared-bucket> --region us-east-1
Grant read access to the target accounts using one of the following options:
Replace <account IDs> with the AWS account IDs where StackSets will deploy the Lambda functions.
Note: The bucket must be in the same region as the StackSet deployment regions. For multi-region deployments, create one bucket per region and run sam package separately for each.
Step 1: Build and Upload Lambda Packages to S3
Run the packaging script from the installation/ directory:
cd installation

# Make script executable (first time only)
chmod +x deploy-stacksets.sh

# Build, package, upload to S3, and generate resolved template
./deploy-stacksets.sh <your-org-shared-bucket>
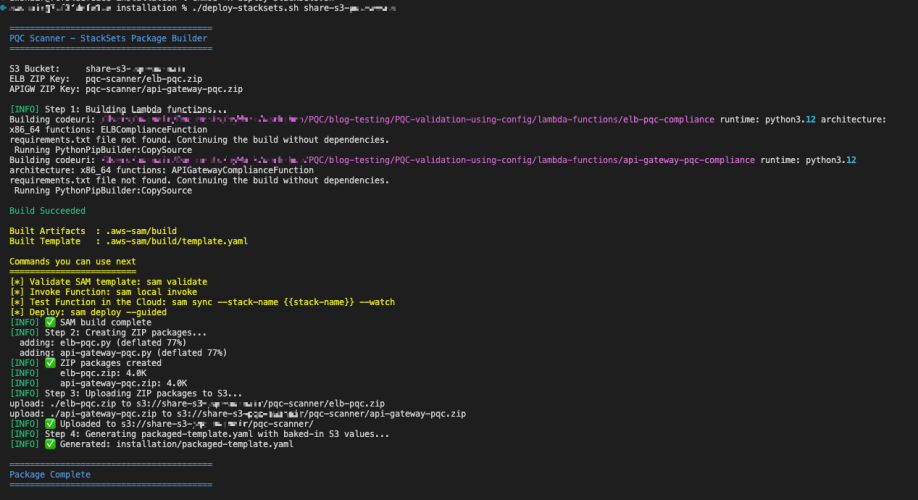
This script automatically:
Builds Lambda functions using SAM
Creates ZIP packages
Uploads ZIPs to the shared S3 bucket
Generates packaged-template.yaml with S3 values baked in (no parameters needed at deploy time)
Figure 4: Sample script output of successful upload of the lambda packages to S3 bucket
Step 2: Deploy Lambda Functions via StackSets
Run the following from the management account (or delegated admin account):
# Create StackSet (--region sets the StackSet "home region" where it is managed)
aws cloudformation create-stack-set \
  --stack-set-name pqc-readiness-lambda-functions \
  --template-body file://packaged-template.yaml \
  --capabilities CAPABILITY_IAM \
  --permission-model SERVICE_MANAGED \
  --auto-deployment Enabled=true,RetainStacksOnAccountRemoval=false \
  --region us-east-1

# Deploy stack instances to member accounts
# --regions = target regions where Lambda functions are deployed in member accounts
# --region  = must match the StackSet home region above
aws cloudformation create-stack-instances \
  --stack-set-name pqc-readiness-lambda-functions \
  --deployment-targets OrganizationalUnitIds=ou-xxxx-xxxxxxxx \
  --regions us-east-1 \
  --region us-east-1
Important — StackSet home region vs deployment regions:
--region (on each CLI command) = the StackSet home region where the StackSet resource lives. Subsequent operations (describe, update, delete) must specify this same region.
--regions (on create-stack-instances) = the deployment target region(s) where stack instances are created in member accounts.
These are independent values. Specify --region explicitly to avoid accidental deployment to your CLI’s default region.
Note: SERVICE_MANAGED StackSets must be created from the management or delegated admin account. The management account itself is excluded from stack instance deployments — use deploy-per-regions.sh separately if you need the scanner in the management account.
This creates Config rules in each member account that reference their local Lambda functions.
Migration guidance and prioritization
The three-tier system provides PQC migration priorities:
High priority – Tier 3 (not PQ-ready):
Target: Resources without PQC support. This includes endpoints not using PQ-ready security policies, endpoints that still allow TLS 1.0 or 1.1.
Action: Upgrade to a PQ-ready policy containing PQ in its name, such as those ending with -PQ-2025-09 (see Elastic Load Balancing security policies documentation for the full list).
Important: Before upgrading to a PQ-ready policy, audit your client TLS versions. PQ-ready policies require TLS 1.3 support; legacy clients that only support TLS 1.2 or earlier will fail to negotiate a connection. Start with a Tier 2 backward-compatible policy (which supports both TLS 1.2 and 1.3 with PQC), monitor connection logs for TLS negotiation failures, and only move to a Tier 1 TLS 1.3-only policy after confirming that your clients support TLS 1.3 with PQC key exchange.
Risk: Endpoints don’t support post-quantum cryptography for data in transit. Legacy TLS protocols are vulnerable to current cryptographic attacks.
Target: Resources using TLS 1.3 + PQ-ready policies that also support TLS 1.2 for backward compatibility.
Action: Consider TLS 1.3-only policies when client compatibility analysis confirms connecting clients support TLS 1.3.
Risk: Minimal. These resources already support PQ-TLS with TLS 1.3 connections. TLS 1.2 and earlier fallback maintains backward compatibility, which might indicate some clients aren’t negotiating in PQ-TLS. Remediation is to monitor logs, identify the volume of these connections and clients and plan migration for these clients to use TLS 1.3 with PQ-TLS.
No action – Tier 1 (PQ-ready, optimal):
Target: Resources using TLS 1.3 only with PQC key exchange: These resources meet the target state. No migration needed.
Viewing the results
In each member account, navigate to AWS Config Console in the deployed region.
Conformance Pack View
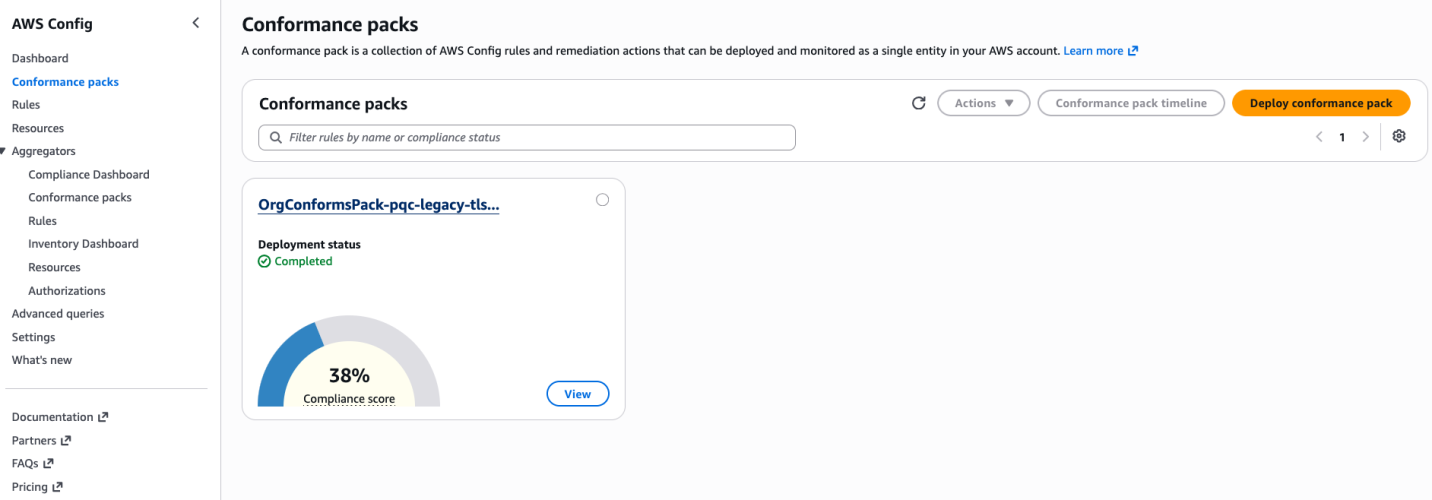
Go to AWS Config → Conformance packs and look for:
OrgConformsPack-pqc-legacy-tls-compliance-
Note: Organization conformance packs are prefixed with OrgConformsPack- and have a random suffix appended (e.g., OrgConformsPack-pqc-legacy-tls-compliance-gyv22je0).
Figure 5: PQC Conformance Pack Compliance Score is the percentage of the number of compliant rule-resource
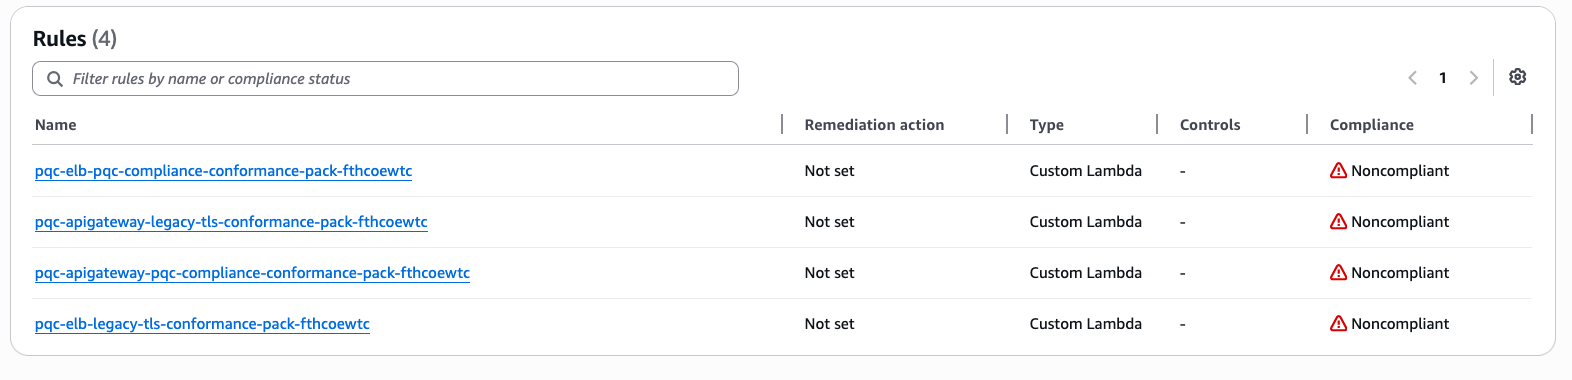
Click the conformance pack to see an overall compliance summary across all 4 rules.
Individual Rules View
Go to AWS Config → Rules and find 4 rules with prefix pqc-:
pqc-elb-pqc-compliance-conformance-pack-
pqc-elb-legacy-tls-conformance-pack-
pqc-apigateway-pqc-compliance-conformance-pack-
pqc-apigateway-legacy-tls-conformance-pack-
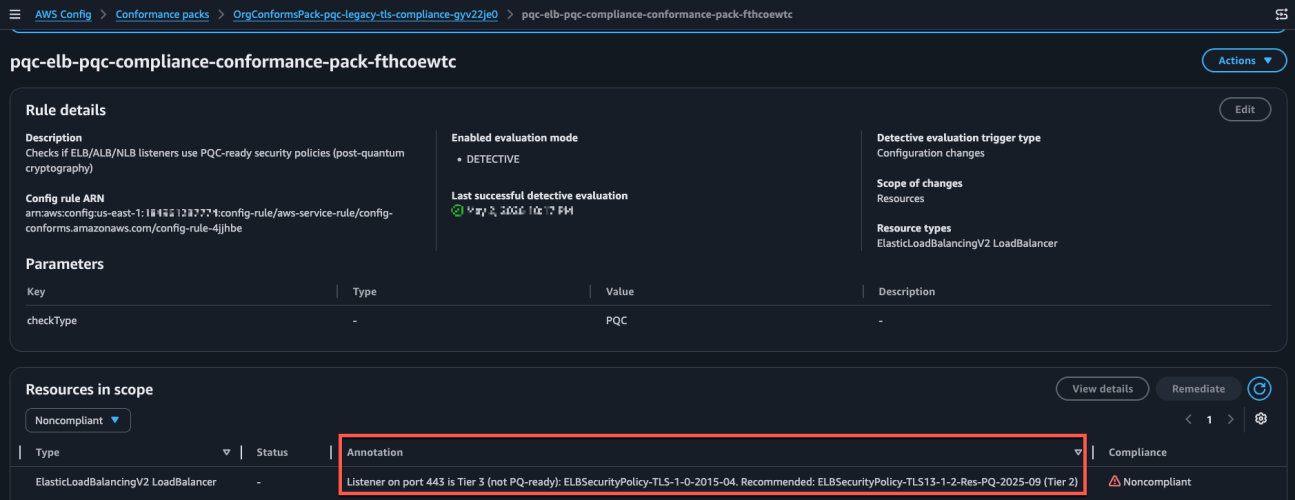
Click any rule to view:
Compliant vs non-compliant resource counts
Detailed annotations for each resource
Resource ARNs and current security policy configurations
Figure 6: Visibility into Config rules status inside the conformance pack
Figure 7: Sample image of the config rule findings and annotation describing the migration guidance based on 3-tier classification.
Conclusion
After deploying the PQC Readiness Scanner, you gain visibility into TLS posture across AWS edge services, which reduces manual configuration reviews. The tier system provides specific upgrade recommendations so teams can understand next steps without cryptographic expertise. The scanner automatically detects configuration changes to help new deployments maintain readiness standards. Built-in AWS Config reporting supports audit requirements and demonstrates measurable progress toward PQC readiness.
Deploy the PQC Readiness Scanner and review your results with PQC Readiness Scanner. Start migration with high priority Tier 3 resources and monitor progress across your accounts using AWS Config aggregators.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS Config re:Post or contact AWS Support.
As outlined in the AWS post-quantum cryptography (PQC) migration plan, addressing the risk of harvest now, decrypt later (HNDL) attack is an important part of your post-quantum plan. Upgrading the client-side of your workloads to support quantum-resistant confidentiality is an important aspect of your side of the PQC shared responsibility model. Timelines to plan and execute your PQC upgrades vary by region and by industry and will depend on your own business risk profile. To learn more, see the AWS PQC frequently asked questions.
AWS Secrets Manager uses SSL/TLS to communicate with AWS resources, currently supporting TLS 1.2 and 1.3 in all AWS Regions. The service supports using TLS 1.3 with hybrid post-quantum key exchange for clients that support this capability. The hybrid post-quantum approach establishes TLS connections by combining traditional cryptography (such as X25519) with post-quantum algorithms (ML-KEM), and helps to protect your secrets against both current classical attacks and future quantum computer threats. Regardless of how your workload accesses Secrets Manager, this client-side software upgrade is the only action you need to take to address risk to secrets from HNDL. Your secrets at rest are already encrypted using keys managed by AWS Key Management Service (AWS KMS). Properly implemented symmetric encryption is considered quantum-resistant; asymmetric cryptography faces quantum threats. To learn more, watch AWS re:Inforce 2025 – Post-Quantum Cryptography Demystified.
To reduce builder effort for client-side upgrades, we’re pleased to announce the following Secrets Manager clients now enable and prefer post-quantum TLS when initiating connections to Secrets Manager: Secrets Manager Agent (v2.0.0 or later), the AWS Lambda extension (v19 or later) and the Secrets Manager CSI Driver (v2.0.0 or later). For SDK-based clients, hybrid post-quantum key exchange is available in supported AWS SDKs. Enablement requirements vary by language, version, and operating system. See the following table for your SDK client.
This launch is part of the ongoing commitment AWS has made to migrate systems to post-quantum cryptography and making it straightforward for our customers to do the same. See Post-Quantum Cryptography to learn more.
The following table summarizes the behavior for each client. When the client is upgraded to support hybrid post-quantum key exchange, the Secrets Manager service endpoint automatically selects it during the TLS handshake. Upgrading to the versions listed in the table is the only action you need to take for your workload to begin using hybrid post-quantum key exchange when calling Secrets Manager APIs.
The AWS SDK for Python (boto3) uses the OS-provided OpenSSL for TLS. Hybrid PQ key exchange in TLS requires running on a system with OpenSSL 3.5 or later installed.
The Secrets Manager caching libraries are built on the AWS SDKs and inherit their TLS behavior. Note for Java: The JDBC driver flag and Java Caching flag must be set to enable Hybrid PQ key exchange in TLS.
If you’re using the Secrets Manager Agent, the Lambda extension, or the CSI Driver, upgrade to the listed version to use hybrid post-quantum key exchange in TLS as the default. Customers using the AWS SDK for Rust, Go, or Node.js at the versions listed in the table are already upgraded and no additional action is required. The SDK will select the hybrid post-quantum key exchange for API calls. For customers using the AWS SDK for Python, hybrid post-quantum key exchange in TLS requires OpenSSL 3.5 or later to be present on the host system. Guidance on verifying and enabling this is available in the AWS Secrets Manager documentation. For customers using the AWS SDK for Java v2, hybrid post-quantum key exchange in TLS requires using the AWS CRT HTTP client. The postQuantumTlsEnabled(true) must be set on the CRT client to enable hybrid post-quantum key exchange in TLS.
After your client versions meet the requirements listed in the table, you can verify that your connections are actively using hybrid post-quantum key exchange.
How to verify your connection uses hybrid post-quantum key exchange
With hybrid post-quantum key exchange using ML-KEM now enabled by default for Secrets Manager clients (see the preceding table), most customers will not need ongoing monitoring to verify correct behavior or detect regressions. However, security teams and compliance officers might want to confirm that their Secrets Manager API calls are negotiating the hybrid key exchange. On the server side, you can confirm hybrid post-quantum key exchange in TLS by using AWS CloudTrail. On the client side, you can inspect TLS handshake details using a utility like Wireshark or by using developer tools built into major web browsers.
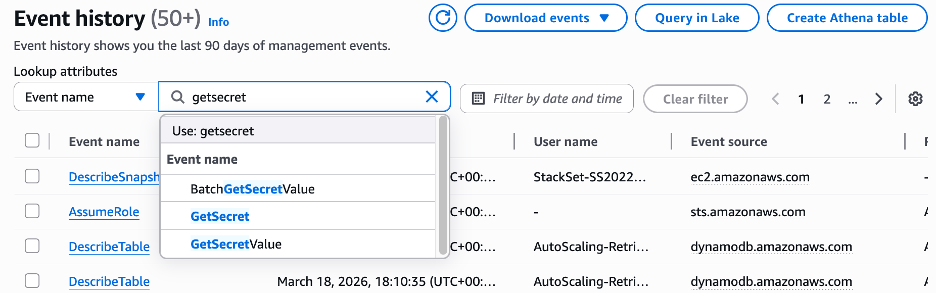
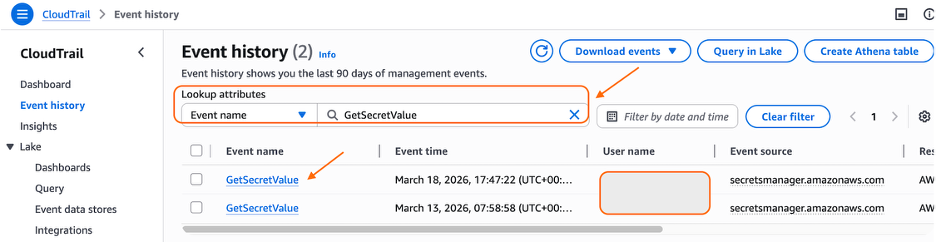
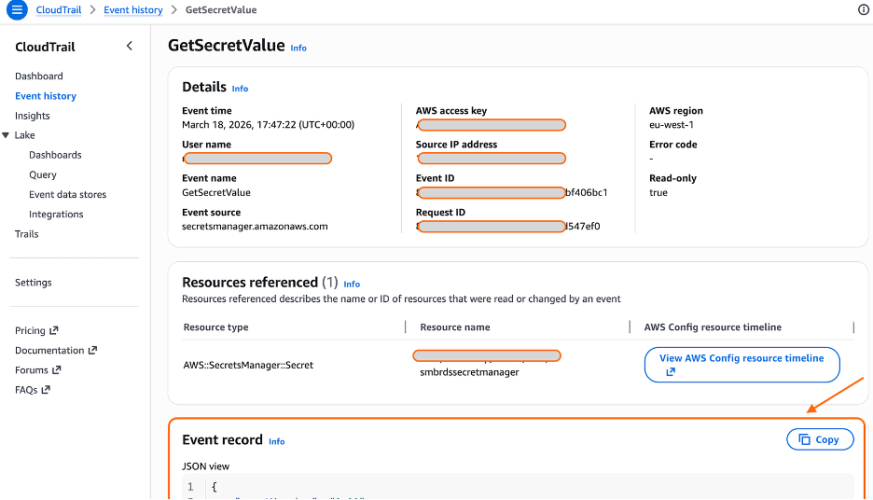
Verification is a two-step process: first, fetch a secret using your Secrets Manager client to generate a GetSecretValue API call, then confirm in AWS CloudTrail that the call negotiated hybrid post-quantum key exchange.
Fetch your secret using your Secrets Manager client
The following examples show how to retrieve your secret using the Secrets Manager Agent, Lambda extension, and CSI Driver—each of which will automatically negotiate hybrid post-quantum key exchange when calling the GetSecretValue API.
To verify hybrid post-quantum TLS with Secrets Manager Agent on EC2 instance: Install the agent on your Amazon Elastic Compute Cloud (Amazon EC2) instance and use it as a client to fetch your secret.
Use the agent to fetch your secret. curl -H “X-Aws-Parameters-Secrets-Token: $(</tmp/awssmatoken)” localhost:2773/secretsmanager/get?secretId=<YOUR-SECRET-ARN>
Wait for about 5 minutes for CloudTrail to deliver the logs.
To verify hybrid post-quantum TLS with Lambda extension: Use the AWS parameters and Secrets Manager Lambda extension to create a Lambda function that will consume your secrets from Secrets Manager using direct API calls.
Confirm hybrid post-quantum key exchange using CloudTrail
CloudTrail logs include a tlsDetails field for Secrets Manager API calls. When hybrid post-quantum key exchange in TLS is active, the keyExchange field in tlsDetails will show X25519MLKEM768. Each CloudTrail record includes a tlsDetails field that contains the cipher suite and, where available, the key exchange group negotiated during the TLS handshake.
If the keyExchange field shows X25519MLKEM768, then hybrid post-quantum key exchange in TLS is active. If it shows a traditional algorithm such as X25519, the client is not advertising ML-KEM support, and you should check the client version and configuration.
Troubleshooting
If your Secrets Manager API calls aren’t negotiating X25519MLKEM768 after updating your clients, check your SDK version, OpenSSL version (Python), and firewall or proxy configuration as shown in the Client Hybrid Post-Quantum Key Exchange Requirements section near the beginning of this post.
What’s next
This launch is one step in a broader migration. AWS is continuing to roll out ML-KEM support across AWS service HTTPS endpoints as part of Workstream 2 of the AWS PQC Migration Plan, with a target of full coverage across public AWS endpoints.
Support for CRYSTALS-Kyber, the pre-standardization predecessor to ML-KEM, is phasing out across AWS endpoints in 2026. Customers on older SDK versions that advertise only CRYSTALS-Kyber support will fall back gracefully to traditional TLS rather than negotiate the deprecated algorithm. To avoid this fallback, upgrade to the SDK versions listed in this post.
The journey of PQC migration extends beyond confidentiality of data in transit. To stay informed about the latest developments in the AWS PQC journey and your side of shared responsibility, follow the AWS Post-Quantum Cryptography page.
Conclusion
AWS Secrets Manager now enables hybrid post-quantum key exchange using ML-KEM by default to help protect your secrets and support your compliance efforts. This update requires no code changes or configuration updates for customers using the latest client versions.
This post covered how AWS Secrets Manager uses hybrid post-quantum cryptography to secure TLS connections, which clients support this capability, and how to verify that your connections are protected against harvest now, decrypt later attacks.
To benefit from this announcement today:
Upgrade your Secrets Manager client (Agent, Lambda extension, or CSI Driver) to the latest available versions to enable hybrid post-quantum key exchange using ML-KEM
If your workload uses the AWS SDK instead of a caching client, upgrade your AWS SDK and underlying dependencies to the minimum versions listed in this post
Verify hybrid post-quantum key exchange in TLS is active by checking the keyExchange field in CloudTrail tlsDetails for your Secrets Manager API calls
Test end-to-end hybrid post-quantum key exchange TLS connectivity in your environment, including network paths that traverse corporate firewalls or proxies
AWS will continue rolling out post-quantum cryptography support. For information about the broader migration effort, see the AWS PQC Migration Plan. Keep an updated cryptographic inventory of your broader environment to identify other uses of traditional public-key cryptography that will require migration. The CISA Quantum-Readiness guidance and the AWS PQC Migration Plan are good starting points.
According to a new law, the Hong Kong police can demand that you reveal the encryption keys protecting your computer, phone, hard drives, etc.—even if you are just transiting the airport.
In a security alert dated March 26, the U.S. Consulate General said that, on March 23, 2026, Hong Kong authorities changed the rules governing enforcement of the National Security Law. Under the revised framework, police can require individuals to provide passwords or other assistance to access personal electronic devices, including cellphones and laptops.
The consulate warned that refusal to comply is now a criminal offense. It also said authorities have expanded powers to take and keep personal electronic devices as evidence if they claim the devices are linked to national security offenses.
Mike Masnick points out that the recent New Mexico court ruling against Meta has some bad implications for end-to-end encryption, and security in general:
If the “design choices create liability” framework seems worrying in the abstract, the New Mexico case provides a concrete example of where it leads in practice.
One of the key pieces of evidence the New Mexico attorney general used against Meta was the company’s 2023 decision to add end-to-end encryption to Facebook Messenger. The argument went like this: predators used Messenger to groom minors and exchange child sexual abuse material. By encrypting those messages, Meta made it harder for law enforcement to access evidence of those crimes. Therefore, the encryption was a design choice that enabled harm.
The state is now seeking court-mandated changes including “protecting minors from encrypted communications that shield bad actors.”
Yes, the end result of the New Mexico ruling might be that Meta is ordered to make everyone’s communications less secure. That should be terrifying to everyone. Even those cheering on the verdict.
End-to-end encryption protects billions of people from surveillance, data breaches, authoritarian governments, stalkers, and domestic abusers. It’s one of the most important privacy and security tools ordinary people have. Every major security expert and civil liberties organization in the world has argued for stronger encryption, not weaker.
But under the “design liability” theory, implementing encryption becomes evidence of negligence, because a small number of bad actors also use encrypted communications. The logic applies to literally every communication tool ever invented. Predators also use the postal service, telephones, and in-person conversation. The encryption itself harms no one. Like infinite scroll and autoplay, it is inert without the choices of bad actors - choices made by people, not by the platform’s design.
The incentive this creates goes far beyond encryption, and it’s bad. If any product improvement that protects the majority of users can be held against you because a tiny fraction of bad actors exploit it, companies will simply stop making those improvements. Why add encryption if it becomes Exhibit A in a future lawsuit? Why implement any privacy-protective feature if a plaintiff’s lawyer will characterize it as “shielding bad actors”?
And it gets worse. Some of the most damaging evidence in both trials came from internal company documents where employees raised concerns about safety risks and discussed tradeoffs. These were played up in the media (and the courtroom) as “smoking guns.” But that means no company is going to allow anyone to raise concerns ever again. That’s very, very bad.
In a sane legal environment, you want companies to have these internal debates. You want engineers and safety teams to flag potential risks, wrestle with difficult tradeoffs, and document their reasoning. But when those good-faith deliberations become plaintiff’s exhibits presented to a jury as proof that “they knew and did it anyway,” the rational corporate response is to stop putting anything in writing. Stop doing risk assessments. Stop asking hard questions internally.
The lesson every general counsel in Silicon Valley is learning right now: ignorance is safer than inquiry. That makes everyone less safe, not more.
The essay has a lot more: about Section 230, about competition in this space, about the myopic nature of the ruling. Go read it.
Matrix is the gold standard for decentralized, end-to-end encrypted communication. It powers government messaging systems, open-source communities, and privacy-focused organizations worldwide.
For the individual developer, however, the appeal is often closer to home: bridging fragmented chat networks (like Discord and Slack) into a single inbox, or simply ensuring your conversation history lives on infrastructure you control. Functionally, Matrix operates as a decentralized, eventually consistent state machine. Instead of a central server pushing updates, homeservers exchange signed JSON events over HTTP, using a conflict resolution algorithm to merge these streams into a unified view of the room’s history.
But there is a “tax” to running it Traditionally, operating a Matrix homeserver has meant accepting a heavy operational burden. You aren’t just installing software; you are becoming a system administrator. You have to provision virtual private servers (VPS), tune PostgreSQL for heavy write loads, manage Redis for caching, configure reverse proxies, and handle rotation for TLS certificates. It’s a stateful, heavy beast that demands to be fed time and money, whether you are sending one message a day or one million.
We wanted to see if we could eliminate that tax entirely.
Spoiler: We could. In this post, we’ll explain how we ported a complete Matrix homeserver to Cloudflare Workers. The result is a serverless architecture where operations disappear, costs scale to zero when idle, and every connection is protected by post-quantum cryptography by default. You can view the source code and deploy your own instance directly from GitHub.
From Tuwunel to Workers
Our starting point was Tuwunel, a Rust-based Matrix homeserver designed for traditional deployments. PostgreSQL for persistence, Redis for caching, filesystem for media. Porting it to Workers meant questioning every storage assumption we’d taken for granted.
The good news: Rust compiles to WebAssembly, and the core Matrix protocol logic — event authorization, room state resolution, cryptographic verification — translated directly. The workers-rs crate bridges the gap to Cloudflare’s runtime.
The challenge was storage. Traditional homeservers assume strong consistency via a central SQL database. Cloudflare offers a powerful alternative: Durable Objects. This primitive gives us the strong consistency and atomicity required for Matrix state resolution, while still allowing the application to run at the edge.
Here’s how the mapping worked out:
From monolith to serverless
Moving to Cloudflare Workers brings several advantages for a developer: simple deployment, lower costs, low latency, and built-in security.
Easy deployment: A traditional Matrix deployment requires server provisioning, PostgreSQL administration, Redis cluster management, TLS certificate renewal, load balancer configuration, monitoring infrastructure, and on-call rotations.
With Workers, deployment is wrangler deploy. We handle TLS, load balancing, DDoS protection, and global distribution. So there’s no server to patch, no database to vacuum, or certificates to renew.
Usage-based costs: Traditional homeservers cost money whether anyone is using them or not. A small community server handling a few hundred requests per day still requires a typical VPS costing around $20/month running 24/7.
Workers pricing is request-based, so low-traffic homeservers cost just pennies. When usage spikes during active conversations, you pay for what you use. When everyone goes to sleep, costs drop toward zero.
Lower latency globally: A traditional Matrix homeserver in us-east-1 adds 200ms+ latency for users in Asia or Europe. Every sync request, message sent, and typing indicator go round-trip to a single region.
Workers, meanwhile, run in 300+ locations worldwide. When a user in Tokyo sends a message, the Worker executes in Tokyo.
Built-in security: Matrix homeservers can be high-value targets: They handle encrypted communications, store message history, and authenticate users. Traditional deployments require careful hardening: firewall configuration, rate limiting, DDoS mitigation, WAF rules, IP reputation filtering.
We provide all of this by default. The Worker never sees attack traffic, because we filter it first. For a solo developer or small team, achieving this level of hardening on a Linux VPS is a full-time job. On Workers, it is the baseline environment.
An adversary captures your encrypted TLS traffic today and stores it. Years from now, when quantum computers can break classical key exchange algorithms, they decrypt everything retroactively. For a messaging platform handling sensitive communications, this isn’t theoretical. Government agencies and well-funded adversaries are already stockpiling encrypted traffic.
Fortunately, we didn’t have to protect against this by ourselves. Cloudflare deployed post-quantum hybrid key agreement across all TLS 1.3 connections in October 2022. Every connection to our Worker automatically negotiates X25519MLKEM768 — a hybrid combining classical X25519 with ML-KEM, the post-quantum algorithm standardized by NIST.
Classical cryptography relies on mathematical problems that are hard for traditional computers but trivial for quantum computers running Shor’s algorithm. ML-KEM is based on lattice problems that remain hard even for quantum computers. The hybrid approach means both algorithms must fail for the connection to be compromised.
Following a message through the system
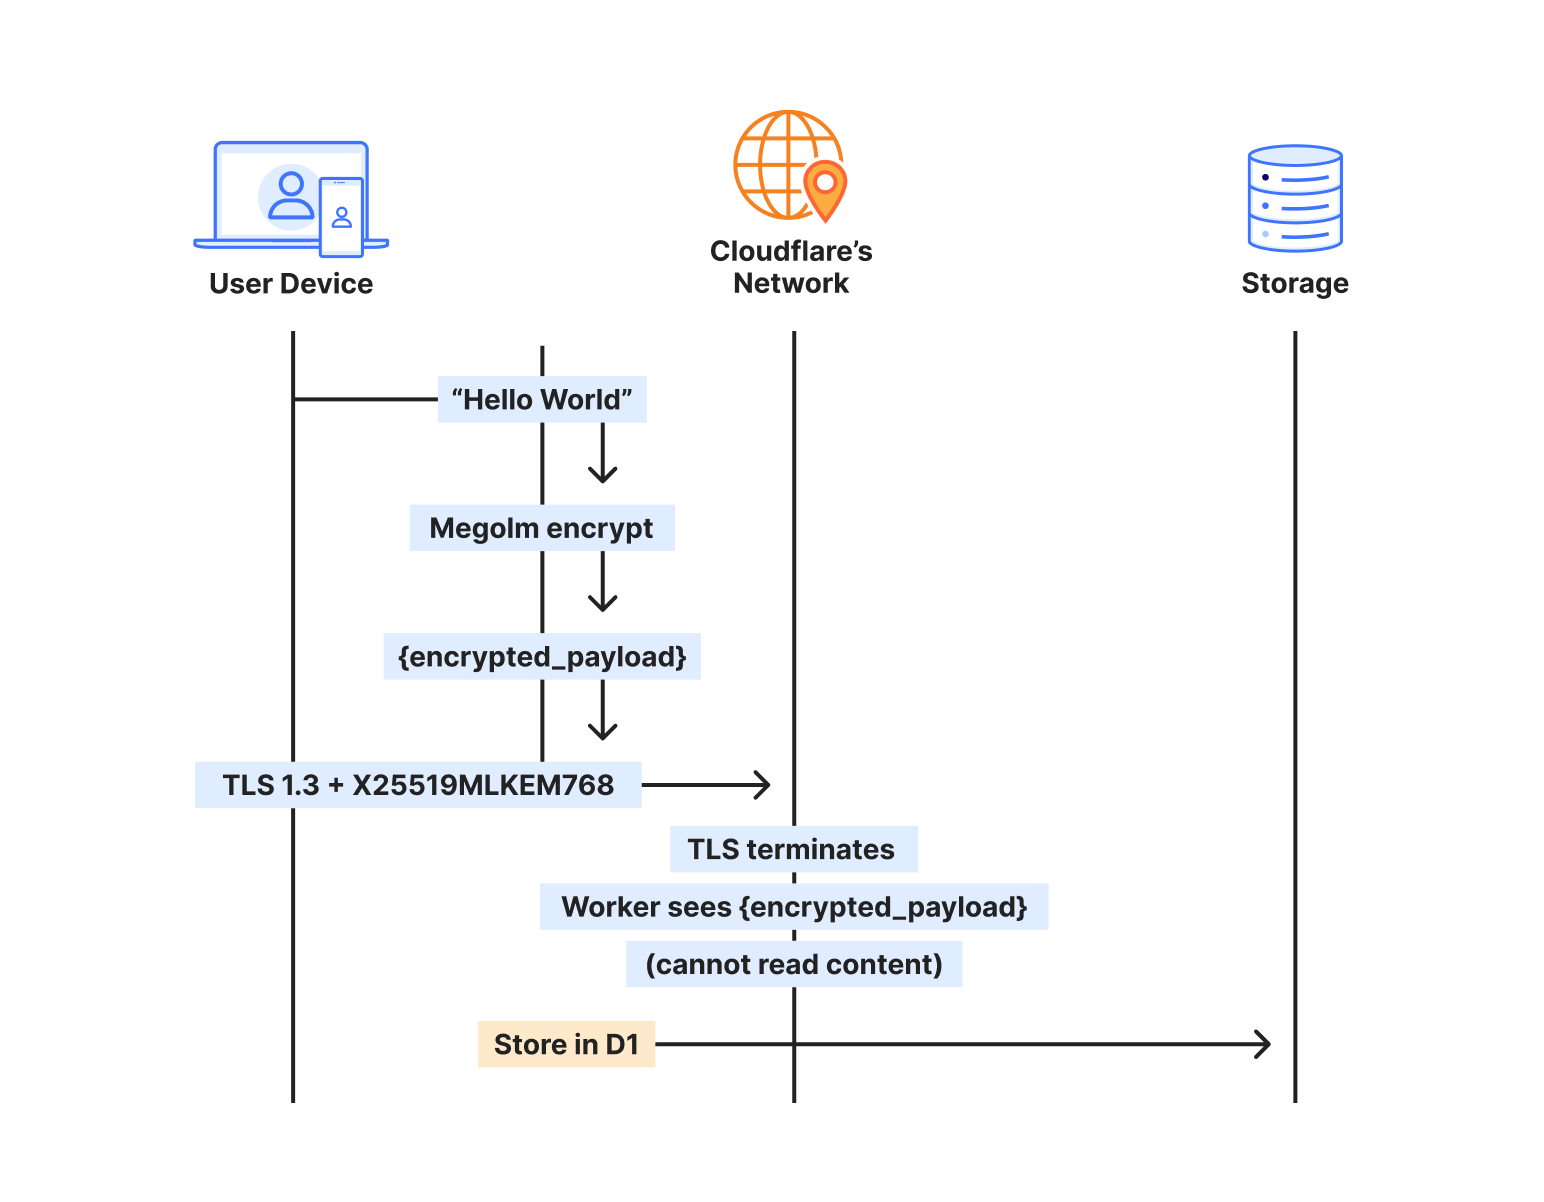
Understanding where encryption happens matters for security architecture. When someone sends a message through our homeserver, here’s the actual path:
The sender’s client takes the plaintext message and encrypts it with Megolm — Matrix’s end-to-end encryption. This encrypted payload then gets wrapped in TLS for transport. On Cloudflare, that TLS connection uses X25519MLKEM768, making it quantum-resistant.
The Worker terminates TLS, but what it receives is still encrypted — the Megolm ciphertext. We store that ciphertext in D1, index it by room and timestamp, and deliver it to recipients. But we never see the plaintext. The message “Hello, world” exists only on the sender’s device and the recipient’s device.
When the recipient syncs, the process reverses. They receive the encrypted payload over another quantum-resistant TLS connection, then decrypt locally with their Megolm session keys.
Two layers, independent protection
This creates defense in depth through two encryption layers that operate independently:
The transport layer (TLS) protects data in transit. It’s encrypted at the client and decrypted at the Cloudflare edge. With X25519MLKEM768, this layer is now post-quantum.
The application layer (Megolm E2EE) protects message content. It’s encrypted on the sender’s device and decrypted only on recipient devices. This uses classical Curve25519 cryptography.
Here’s why this architecture matters: Even if Matrix E2EE is eventually broken by quantum computers, the message content was never transmitted in a quantum-vulnerable form. The TLS layer that carried the E2EE ciphertext was itself post-quantum secured.
The post-quantum TLS acts as a quantum-resistant envelope around everything, including the classical E2EE layer. This buys time for the Matrix protocol to migrate to post-quantum E2EE algorithms without leaving current communications vulnerable to harvest-now-decrypt-later attacks.
Who sees what
Any Matrix homeserver operator — whether running Synapse on a VPS or this implementation on Workers — can see metadata: which rooms exist, who’s in them, when messages were sent. This is inherent to operating the server. You’re the operator; you control the infrastructure.
What no one in the infrastructure chain can see: message content. The E2EE payload is encrypted on sender devices before it ever hits the network. Cloudflare terminates TLS and passes requests to your Worker, but both see only Megolm ciphertext. Media in encrypted rooms is encrypted client-side before upload. Private keys never leave user devices.
The server processes ciphertext, not conversations. That’s true whether you’re self-hosting on bare metal or running on Workers.
What traditional deployments would need
Achieving post-quantum TLS on a traditional Matrix deployment would require upgrading OpenSSL or BoringSSL to a version supporting ML-KEM, configuring cipher suite preferences correctly, testing client compatibility across all Matrix apps, monitoring for TLS negotiation failures, staying current as PQC standards evolve, and handling clients that don’t support PQC gracefully.
With Workers, it’s automatic. Chrome, Firefox, and Edge all support X25519MLKEM768. Mobile apps using platform TLS stacks inherit this support. The security posture improves as Cloudflare’s PQC deployment expands — no action required on our part.
The storage architecture that made it work
The key insight from porting Tuwunel was that different data needs different consistency guarantees. We use each Cloudflare primitive for what it does best.
D1 for the data model
D1 stores everything that needs to survive restarts and support queries: users, rooms, events, device keys. Over 25 tables covering the full Matrix data model.
CREATE TABLE events (
	event_id TEXT PRIMARY KEY,
	room_id TEXT NOT NULL,
	sender TEXT NOT NULL,
	event_type TEXT NOT NULL,
	state_key TEXT,
	content TEXT NOT NULL,
	origin_server_ts INTEGER NOT NULL,
	depth INTEGER NOT NULL
);
D1’s SQLite foundation meant we could port Tuwunel’s queries with minimal changes. Joins, indexes, and aggregations work as expected.
We learned one hard lesson: D1’s eventual consistency breaks foreign key constraints. A write to rooms might not be visible when a subsequent write to events checks the foreign key — different replicas, different views of the world. We removed all foreign keys and enforce referential integrity in application code.
KV for ephemeral state
OAuth authorization codes live for 10 minutes. Refresh tokens last for a session. None of this needs SQL — it needs fast key-value access with automatic expiration.
// Store OAuth code with 10-minute TTL
kv.put(&format!("oauth_code:{}", code), &token_data)?
	.expiration_ttl(600)
	.execute()
	.await?;
KV’s global distribution means OAuth flows work fast regardless of where users are located.
R2 for media
Matrix media maps directly to R2. Upload an image, get back a content-addressed URL. Egress is free, which matters for a protocol where clients frequently download the same avatars and images.
Durable Objects for atomicity
Some operations can’t tolerate eventual consistency. When a client claims a one-time encryption key, that key must be atomically removed. If two clients claim the same key, encrypted session establishment fails.
Durable Objects provide single-threaded, strongly consistent storage:
#[durable_object]
pub struct UserKeysObject {
	state: State,
	env: Env,
}

impl UserKeysObject {
	async fn claim_otk(&self, algorithm: &str) -> Result<Option<Key>> {
    	// Atomic within single DO - no race conditions possible
    	let mut keys: Vec<Key> = self.state.storage()
        	.get("one_time_keys")
        	.await
        	.ok()
        	.flatten()
        	.unwrap_or_default();

    	if let Some(idx) = keys.iter().position(|k| k.algorithm == algorithm) {
        	let key = keys.remove(idx);
        	self.state.storage().put("one_time_keys", &keys).await?;
        	return Ok(Some(key));
    	}
    	Ok(None)
	}
}
We use UserKeysObject for E2EE key management, RoomObject for real-time room events like typing indicators and read receipts, and UserSyncObject for to-device message queues. The rest flows through D1.
Complete E2EE, complete OAuth
End-to-end encryption is non-negotiable for secure communications. Our implementation supports the full Matrix E2EE stack: device keys, cross-signing keys, one-time keys, fallback keys, key backup, and dehydrated devices.
Modern Matrix clients use OAuth 2.0/OIDC instead of legacy password flows. We implemented a complete OAuth provider: dynamic client registration, PKCE authorization, RS256-signed JWT tokens, token refresh with rotation, and standard OIDC discovery endpoints.
Point Element or any Matrix client at the domain, and it discovers everything automatically.
Sliding Sync for mobile
Traditional Matrix sync transfers megabytes of data on initial connection — every room, every state event, recent timeline for each. This destroys mobile battery and data plans.
Sliding Sync lets clients request exactly what they need. Instead of downloading everything, clients get the 20 most recent rooms with minimal state. As users scroll, they request more ranges. The server tracks position and sends only deltas.
Combined with edge execution, mobile clients can connect and render their room list in under 500ms — even on slow networks.
The comparison
For a homeserver serving a small team:
Traditional (VPS)
Workers
Monthly cost (idle)
$20-50
<$1
Monthly cost (active)
$20-50
$3-10
Global latency
100-300ms
20-50ms
Time to deploy
Hours
Seconds
Maintenance
Weekly
None
DDoS protection
Additional cost
Included
Post-quantum TLS
Complex setup
Automatic
*Based on public rates and metrics published by DigitalOcean, AWS Lightsail, and Linode as of January 15, 2026.
The economics improve further at scale. Traditional deployments require capacity planning and over-provisioning. Workers scale automatically.
The future of decentralized protocols
When we started this project, the goal was simply to see if the pieces would fit. Could a protocol as complex and stateful as Matrix — designed for heavy iron and persistent file systems — actually run on an ephemeral, serverless edge?
The answer is yes, but the implication is bigger than just Matrix.
By mapping traditional stateful components to Cloudflare’s primitives — Postgres to D1, Redis to KV, mutexes to Durable Objects — we proved that complex applications don’t need complex infrastructure. We stripped away the operating system, the database management, and the network configuration, leaving only the application logic and the data itself.
This architecture shifts the paradigm for self-hosting. It turns “running a server” from a chore into a utility. You get the sovereignty of owning your data without the burden of owning the infrastructure.
Matrix on Workers runs in production today, handling real encrypted communications for our team. It is fast, it is cheap, and it is arguably one of the most secure ways to deploy a homeserver today.
Ready to build secure, real-time applications on Workers? Get started withCloudflare Workers and exploreDurable Objects for your own stateful edge applications. Join ourDiscord community to connect with other developers building at the edge.
After twenty-six years, Microsoft is finally upgrading the last remaining instance of the encryption algorithm RC4 in Windows.
of the most visible holdouts in supporting RC4 has been Microsoft. Eventually, Microsoft upgraded Active Directory to support the much more secure AES encryption standard. But by default, Windows servers have continued to respond to RC4-based authentication requests and return an RC4-based response. The RC4 fallback has been a favorite weakness hackers have exploited to compromise enterprise networks. Use of RC4 played a key role in last year’s breach of health giant Ascension. The breach caused life-threatening disruptions at 140 hospitals and put the medical records of 5.6 million patients into the hands of the attackers. US Senator Ron Wyden (D-Ore.) in September called on the Federal Trade Commission to investigate Microsoft for “gross cybersecurity negligence,” citing the continued default support for RC4.
Last week, Microsoft said it was finally deprecating RC4 and cited its susceptibility to Kerberoasting, the form of attack, known since 2014, that was the root cause of the initial intrusion into Ascension’s network.
Fun fact: RC4 was a trade secret until I published the algorithm in the second edition of Applied Cryptography in 1995.
Abstract: In this article, I investigate the hypothesis that the Voynich Manuscript (MS 408, Yale University Beinecke Library) is compatible with being a ciphertext by attempting to develop a historically plausible cipher that can replicate the manuscript’s unusual properties. The resulting ciphera verbose homophonic substitution cipher I call the Naibbe ciphercan be done entirely by hand with 15th-century materials, and when it encrypts a wide range of Latin and Italian plaintexts, the resulting ciphertexts remain fully decipherable and also reliably reproduce many key statistical properties of the Voynich Manuscript at once. My results suggest that the so-called “ciphertext hypothesis” for the Voynich Manuscript remains viable, while also placing constraints on plausible substitution cipher structures.
The International Association of Cryptologic Research—the academic cryptography association that’s been putting conferences like Crypto (back when “crypto” meant “cryptography”) and Eurocrypt since the 1980s—had to nullify an online election when trustee Moti Yung lost his decryption key.
For this election and in accordance with the bylaws of the IACR, the three members of the IACR 2025 Election Committee acted as independent trustees, each holding a portion of the cryptographic key material required to jointly decrypt the results. This aspect of Helios’ design ensures that no two trustees could collude to determine the outcome of an election or the contents of individual votes on their own: all trustees must provide their decryption shares.
Unfortunately, one of the three trustees has irretrievably lost their private key, an honest but unfortunate human mistake, and therefore cannot compute their decryption share. As a result, Helios is unable to complete the decryption process, and it is technically impossible for us to obtain or verify the final outcome of this election.
The group will redo the election, but this time setting a 2-of-3 threshold scheme for decrypting the results, instead of requiring all three
The Business of Secrets: Adventures in Selling Encryption Around the World by Fred Kinch (May 24, 2024)
From the vantage point of today, it’s surreal reading about the commercial cryptography business in the 1970s. Nobody knew anything. The manufacturers didn’t know whether the cryptography they sold was any good. The customers didn’t know whether the crypto they bought was any good. Everyone pretended to know, thought they knew, or knew better than to even try to know.
The Business of Secrets is the self-published memoirs of Fred Kinch. He was founder and vice president of—mostly sales—at a US cryptographic hardware company called Datotek, from company’s founding in 1969 until 1982. It’s mostly a disjointed collection of stories about the difficulties of selling to governments worldwide, along with descriptions of the highs and (mostly) lows of foreign airlines, foreign hotels, and foreign travel in general. But it’s also about encryption.
Datotek sold cryptographic equipment in the era after rotor machines and before modern academic cryptography. The company initially marketed computer-file encryption, but pivoted to link encryption—low-speed data, voice, fax—because that’s what the market wanted.
These were the years where the NSA hired anyone promising in the field, and routinely classified—and thereby blocked—publication of academic mathematics papers of those they didn’t hire. They controlled the fielding of strong cryptography by aggressively using the International Traffic in Arms regulation. Kinch talks about the difficulties in getting an expert license for Datotek’s products; he didn’t know that the only reason he ever got that license was because the NSA was able to break his company’s stuff. He had no idea that his largest competitor, the Swiss company Crypto AG, was owned and controlled by the CIA and its West German equivalent. “Wouldn’t that have made our life easier if we had known that back in the 1970s?” Yes, it would. But no one knew.
Glimmers of the clandestine world peek out of the book. Countries like France ask detailed tech questions, borrow or buy a couple of units for “evaluation,” and then disappear again. Did they break the encryption? Did they just want to see what their adversaries were using? No one at Datotek knew.
Kinch “carried the key generator logic diagrams and schematics” with him—even today, it’s good practice not to rely on their secrecy for security—but the details seem laughably insecure: four linear shift registers of 29, 23, 13, and 7 bits, variable stepping, and a small nonlinear final transformation. The NSA probably used this as a challenge to its new hires. But Datotek didn’t know that, at the time.
Kinch writes: “The strength of the cryptography had to be accepted on trust and only on trust.” Yes, but it’s so, so weird to read about it in practice. Kinch demonstrated the security of his telephone encryptors by hooking a pair of them up and having people listen to the encrypted voice. It’s rather like demonstrating the safety of a food additive by showing that someone doesn’t immediately fall over dead after eating it. (In one absolutely bizarre anecdote, an Argentine sergeant with a “hearing defect” could understand the scrambled analog voice. Datotek fixed its security, but only offered the upgrade to the Argentines, because no one else complained. As I said, no one knew anything.)
In his postscript, he writes that even if the NSA could break Datotek’s products, they were “vastly superior to what [his customers] had used previously.” Given that the previous devices were electromechanical rotor machines, and that his primary competition was a CIA-run operation, he’s probably right. But even today, we know nothing about any other country’s cryptanalytic capabilities during those decades.
A lot of this book has a “you had to be there” vibe. And it’s mostly tone-deaf. There is no real acknowledgment of the human-rights-abusing countries on Datotek’s customer list, and how their products might have assisted those governments. But it’s a fascinating artifact of an era before commercial cryptography went mainstream, before academic cryptography became approved for US classified data, before those of us outside the triple fences of the NSA understood the mathematics of cryptography.
Ultimately, the architects settled on a creative solution. Rather than bolt KEM onto the existing double ratchet, they allowed it to remain more or less the same as it had been. Then they used the new quantum-safe ratchet to implement a parallel secure messaging system.
Now, when the protocol encrypts a message, it sources encryption keys from both the classic Double Ratchet and the new ratchet. It then mixes the two keys together (using a cryptographic key derivation function) to get a new encryption key that has all of the security of the classical Double Ratchet but now has quantum security, too.
The Signal engineers have given this third ratchet the formal name: Sparse Post Quantum Ratchet, or SPQR for short. The third ratchet was designed in collaboration with PQShield, AIST, and New York University. The developers presented the erasure-code-based chunking and the high-level Triple Ratchet design at the Eurocrypt 2025 conference. At the Usenix 25 conference, they discussed the six options they considered for adding quantum-safe forward secrecy and post-compromise security and why SPQR and one other stood out. Presentations at the NIST PQC Standardization Conference and the Cryptographic Applications Workshop explain the details of chunking, the design challenges, and how the protocol had to be adapted to use the standardized ML-KEM.
Jacomme further observed:
The final thing interesting for the triple ratchet is that it nicely combines the best of both worlds. Between two users, you have a classical DH-based ratchet going on one side, and fully independently, a KEM-based ratchet is going on. Then, whenever you need to encrypt something, you get a key from both, and mix it up to get the actual encryption key. So, even if one ratchet is fully broken, be it because there is now a quantum computer, or because somebody manages to break either elliptic curves or ML-KEM, or because the implementation of one is flawed, or…, the Signal message will still be protected by the second ratchet. In a sense, this update can be seen, of course simplifying, as doubling the security of the ratchet part of Signal, and is a cool thing even for people that don’t care about quantum computers.
We pointed a commercial-off-the-shelf satellite dish at the sky and carried out the most comprehensive public study to date of geostationary satellite communication. A shockingly large amount of sensitive traffic is being broadcast unencrypted, including critical infrastructure, internal corporate and government communications, private citizens’ voice calls and SMS, and consumer Internet traffic from in-flight wifi and mobile networks. This data can be passively observed by anyone with a few hundred dollars of consumer-grade hardware. There are thousands of geostationary satellite transponders globally, and data from a single transponder may be visible from an area as large as 40% of the surface of the earth.
Today’s world requires us to make complex and nuanced decisions about our digital security. Evaluating when to use a secure messaging app like Signal or WhatsApp, which passwords to store on your smartphone, or what to share on social media requires us to assess risks and make judgments accordingly. Arriving at any conclusion is an exercise in threat modeling.
In security, threat modeling is the process of determining what security measures make sense in your particular situation. It’s a way to think about potential risks, possible defenses, and the costs of both. It’s how experts avoid being distracted by irrelevant risks or overburdened by undue costs.
We threat model all the time. We might decide to walk down one street instead of another, or use an internet VPN when browsing dubious sites. Perhaps we understand the risks in detail, but more likely we are relying on intuition or some trusted authority. But in the U.S. and elsewhere, the average person’s threat model is changing—specifically involving how we protect our personal information. Previously, most concern centered on corporate surveillance; companies like Google and Facebook engaging in digital surveillance to maximize their profit. Increasingly, however, many people are worried about government surveillance and how the government could weaponize personal data.
Since the beginning of this year, the Trump administration’s actions in this area have raised alarm bells: The Department of Government Efficiency (DOGE) tookdata from federal agencies, Palantir combined disparate streams of government data into a single system, and Immigration and Customs Enforcement (ICE) used social media posts as a reason to deny someone entry into the U.S.
These threats, and others posed by a techno-authoritarian regime, are vastly different from those presented by a corporate monopolistic regime—and different yet again in a society where both are working together. Contending with these new threats requires a different approach to personal digital devices, cloud services, social media, and data in general.
What Data Does the Government Already Have?
For years, most public attention has centered on the risks of tech companies gathering behavioral data. This is an enormous amount of data, generally used to predict and influence consumers’ future behavior—rather than as a means of uncovering our past. Although commercial data is highly intimate—such as knowledge of your precise location over the course of a year, or the contents of every Facebook post you have ever created—it’s not the same thing as tax returns, police records, unemployment insurance applications, or medical history.
The U.S. government holds extensive data about everyone living inside its borders, some of it very sensitive—and there’s not much that can be done about it. This information consists largely of facts that people are legally obligated to tell the government. The IRS has a lot of very sensitive data about personal finances. The Treasury Department has data about any money received from the government. The Office of Personnel Management has an enormous amount of detailed information about government employees—including the very personal form required to get a security clearance. The Census Bureau possesses vast data about everyone living in the U.S., including, for example, a database of real estate ownership in the country. The Department of Defense and the Bureau of Veterans Affairs have data about present and former members of the military, the Department of Homeland Security has travel information, and various agencies possess health records. And so on.
It is safe to assume that the government has—or will soon have—access to all of this government data. This sounds like a tautology, but in the past, the U.S. government largely followed the many laws limiting how those databases were used, especially regarding how they were shared, combined, and correlated. Under the second Trump administration, this no longer seems to be the case.
Augmenting Government Data with Corporate Data
The mechanisms of corporate surveillance haven’t gone away. Compute technology is constantly spying on its users—and that data is being used to influence us. Companies like Google and Meta are vast surveillance machines, and they use that data to fuel advertising. A smartphone is a portable surveillance device, constantly recording things like location and communication. Cars, and many other Internet of Things devices, do the same. Credit card companies, health insurers, internet retailers, and social media sites all have detailed data about you—and there is a vast industry that buys and sells this intimate data.
This isn’t news. What’s different in a techno-authoritarian regime is that this data is also shared with the government, either as a paid service or as demanded by local law. Amazon shares Ring doorbell data with the police. Flock, a company that collects license plate data from cars around the country, shares data with the police as well. And just as Chinese corporations share user data with the government and companies like Verizon shared calling records with the National Security Agency (NSA) after the Sept. 11 terrorist attacks, an authoritarian government will use this data as well.
Personal Targeting Using Data
The government has vast capabilities for targeted surveillance, both technically and legally. If a high-level figure is targeted by name, it is almost certain that the government can access their data. The government will use its investigatory powers to the fullest: It will go through government data, remotely hack phones and computers, spy on communications, and raid a home. It will compel third parties, like banks, cell providers, email providers, cloud storage services, and social media companies, to turn over data. To the extent those companies keep backups, the government will even be able to obtain deleted data.
This data can be used for prosecution—possibly selectively. This has been made evident in recent weeks, as the Trump administration personally targeted perceived enemies for “mortgage fraud.” This was a clear example of weaponization of data. Given all the data the government requires people to divulge, there will be something there to prosecute.
Although alarming, this sort of targeted attack doesn’t scale. As vast as the government’s information is and as powerful as its capabilities are, they are not infinite. They can be deployed against only a limited number of people. And most people will never be that high on the priorities list.
The Risks of Mass Surveillance
Mass surveillance is surveillance without specific targets. For most people, this is where the primary risks lie. Even if we’re not targeted by name, personal data could raise red flags, drawing unwanted scrutiny.
The risks here are twofold. First, mass surveillance could be used to singleout people to harass or arrest: when they cross the border, show up at immigration hearings, attend a protest, are stopped by the police for speeding, or just as they’re living their normal lives. Second, mass surveillance could be used to threaten or blackmail. In the first case, the government is using that database to find a plausible excuse for its actions. In the second, it is looking for an actual infraction that it could selectively prosecute—or not.
Mitigating these risks is difficult, because it would require not interacting with either the government or corporations in everyday life—and living in the woods without any electronics isn’t realistic for most of us. Additionally, this strategy protects only future information; it does nothing to protect the information generated in the past. That said, going back and scrubbing social media accounts and cloud storage does have some value. Whether it’s right for you depends on your personal situation.
Opportunistic Use of Data
Beyond data given to third parties—either corporations or the government—there is also data users keep in their possession.This data may be stored on personal devices such as computers and phones or, more likely today, in some cloud service and accessible from those devices. Here, the risks are different: Some authority could confiscate your device and look through it.
This is not just speculative. There are many stories of ICE agents examining people’s phones and computers when they attempt to enter the U.S.: their emails, contact lists, documents, photos, browser history, and social media posts.
There are several different defenses you can deploy, presented from least to most extreme. First, you can scrub devices of potentially incriminating information, either as a matter of course or before entering a higher-risk situation. Second, you could consider deleting—even temporarily—social media and other apps so that someone with access to a device doesn’t get access to those accounts—this includes your contacts list. If a phone is swept up in a government raid, your contacts become their next targets.
Third, you could choose not to carry your device with you at all, opting instead for a burner phone without contacts, email access, and accounts, or go electronics-free entirely. This may sound extreme—and getting it right is hard—but I know many people today who have stripped-down computers and sanitized phones for international travel. At the same time, there are also stories of people being denied entry to the U.S. because they are carrying what is obviously a burner phone—or no phone at all.
Encryption Isn’t a Magic Bullet—But Use It Anyway
Encryption protects your data while it’s not being used, and your devices when they’re turned off. This doesn’t help if a border agent forces you to turn on your phone and computer. And it doesn’t protect metadata, which needs to be unencrypted for the system to function. This metadata can be extremely valuable. For example, Signal, WhatsApp, and iMessage all encrypt the contents of your text messages—the data—but information about who you are texting and when must remain unencrypted.
Also, if the NSA wants access to someone’s phone, it can get it. Encryption is no help against that sort of sophisticated targeted attack. But, again, most of us aren’t that important and even the NSA can target only so many people. What encryption safeguards against is mass surveillance.
I recommend Signal for text messages above all other apps. But if you are in a country where having Signal on a device is in itself incriminating, then use WhatsApp. Signal is better, but everyone has WhatsApp installed on their phones, so it doesn’t raise the same suspicion. Also, it’s a no-brainer to turn on your computer’s built-in encryption: BitLocker for Windows and FileVault for Macs.
On the subject of data and metadata, it’s worth noting that data poisoning doesn’t help nearly as much as you might think. That is, it doesn’t do much good to add hundreds of random strangers to an address book or bogus internet searches to a browser history to hide the real ones. Modern analysis tools can see through all of that.
Shifting Risks of Decentralization
This notion of individual targeting, and the inability of the government to do that at scale, starts to fail as the authoritarian system becomes more decentralized. After all, if repression comes from the top, it affects only senior government officials and people who people in power personally dislike. If it comes from the bottom, it affects everybody. But decentralization looks much like the events playing out with ICE harassing, detaining, and disappearing people—everyone has to fear it.
This can go much further. Imagine there is a government official assigned to your neighborhood, or your block, or your apartment building. It’s worth that person’s time to scrutinize everybody’s social media posts, email, and chat logs. For anyone in that situation, limiting what you do online is the only defense.
Being Innocent Won’t Protect You
This is vital to understand. Surveillance systems and sorting algorithms make mistakes. This is apparent in the fact that we are routinely served advertisements for products that don’t interest us at all. Those mistakes are relatively harmless—who cares about a poorly targeted ad?—but a similar mistake at an immigration hearing can get someone deported.
An authoritarian government doesn’t care. Mistakes are a feature and not a bug of authoritarian surveillance. If ICE targets only people it can go after legally, then everyone knows whether or not they need to fear ICE. If ICE occasionally makes mistakes by arresting Americans and deporting innocents, then everyone has to fear it. This is by design.
Effective Opposition Requires Being Online
For most people, phones are an essential part of daily life. If you leave yours at home when you attend a protest, you won’t be able to film police violence. Or coordinate with your friends and figure out where to meet. Or use a navigation app to get to the protest in the first place.
Threat modeling is all about trade-offs. Understanding yours depends not only on the technology and its capabilities but also on your personal goals. Are you trying to keep your head down and survive—or get out? Are you wanting to protest legally? Are you doing more, maybe throwing sand into the gears of an authoritarian government, or even engaging in active resistance? The more you are doing, the more technology you need—and the more technology will be used against you. There are no simple answers, only choices.
The Internet is in constant motion. Sites scale, traffic shifts, and attackers adapt. Security that worked yesterday may not be enough tomorrow. That’s why the technologies that protect the web — such as Transport Layer Security (TLS) and emerging post-quantum cryptography (PQC) — must also continue to evolve. We want to make sure that everyone benefits from this evolution automatically, so we enabled the strongest protections by default.
During Birthday Week 2024, we announced Automatic SSL/TLS: a service that scans origin server configurations of domains behind Cloudflare, and automatically upgrades them to the most secure encryption mode they support. In the past year, this system has quietly strengthened security for more than 6 million domains — ensuring Cloudflare can always connect to origin servers over the safest possible channel, without customers lifting a finger.
Now, a year after we started enabling Automatic SSL/TLS, we want to talk about these results, why they matter, and how we’re preparing for the next leap in Internet security.
The Basics: TLS protocol
Before diving in, let’s review the basics of Transport Layer Security (TLS). The protocol allows two strangers (like a client and server) to communicate securely.
Every secure web session begins with a TLS handshake. Before a single byte of your data moves across the Internet, servers and clients need to agree on a shared secret key that will protect the confidentiality and integrity of your data. The key agreement handshake kicks off with a TLS ClientHello message. This message is the browser/client announcing, “Here’s who I want to talk to (via SNI), and here are the key agreement methods I understand.” The server then proves who it is with its own credentials in the form of a certificate, and together they establish a shared secret key that will protect everything that follows.
TLS 1.3 added a clever shortcut: instead of waiting to be told which method to use for the shared key agreement, the browser can guess what key agreement the server supports, and include one or more keyshares right away. If the guess is correct, the handshake skips an extra round trip and the secure connection is established more quickly. If the guess is wrong, the server responds with a HelloRetryRequest (HRR), telling the browser which key agreement method to retry with. This speculative guessing is a major reason TLS 1.3 is so much faster than TLS 1.2.
Once both sides agree, the chosen keyshare is used to create a shared secret that encrypts the messages they exchange and allows only the right parties to decrypt them.
The nitty-gritty details of key agreement
Up until recently, most of these handshakes have relied on elliptic curve cryptography (ECC) using a curve known as X25519. But looming on the horizon are quantum computers, which could one day break ECC algorithms like X25519 and others. To prepare, the industry is shifting toward post-quantum key agreement with MLKEM, deployed in a hybrid mode (X25519 + MLKEM). This ensures that even if quantum machines arrive, harvested traffic today can’t be decrypted tomorrow. X25519 + MLKEM is steadily rising to become the most popular key agreement for connections to Cloudflare.
The TLS handshake model is the foundation for how we encrypt web communications today. The history of TLS is really the story of iteration under pressure. It’s a protocol that had to keep evolving, so trust on the web could keep pace with how Internet traffic has changed. It’s also what makes technologies like Cloudflare’s Automatic SSL/TLS possible, by abstracting decades of protocol battles and crypto engineering into a single click, so customer websites can be secured by default without requiring every operator to be a cryptography expert.
History Lesson: Stumbles and Standards
Early versions of TLS (then called SSL) in the 1990s suffered from weak keys, limited protection against attacks like man-in-the-middle, and low adoption on the Internet. To stabilize things, the IETF stepped in and released TLS 1.0, followed by TLS 1.1 and 1.2 through the 2000s. These versions added stronger ciphers and patched new attack vectors, but years of fixes and extensions left the protocol bloated and hard to evolve.
The early 2010s marked a turning point. After the Snowden disclosures, the Internet doubled down on encryption by default. Initiatives like Let’s Encrypt, the mass adoption of HTTPS, and Cloudflare’s own commitment to offer SSL/TLS for free turned encryption from optional, expensive, and complex into an easy baseline requirement for a safer Internet.
All of this momentum led to TLS 1.3 (2018), which cut away legacy baggage, locked in modern cipher suites, and made encrypted connections nearly as fast as the underlying transport protocols like TCP—and sometimes even faster with QUIC.
The CDN Twist
As Content Delivery Networks (CDNs) rose to prominence, they reshaped how TLS was deployed. Instead of a browser talking directly to a distant server hosting content (what Cloudflare calls an origin), it now spoke to the nearest edge data center, which may in-turn speak to an origin server on the client’s behalf.
This created two distinct TLS layers:
Edge ↔ Browser TLS: The front door, built to quickly take on new improvements in security and performance. Edges and browsers adopt modern protocols (TLS 1.3, QUIC, session resumption) to cut down on latency.
Edge ↔ Origin TLS: The backhaul, which must be more flexible. Origins might be older, more poorly maintained, run legacy TLS stacks, or require custom certificate handling.
In practice, CDNs became translators: modernizing encryption at the edge while still bridging to legacy origins. It’s why you can have a blazing-fast TLS 1.3 session from your phone, even if the origin server behind the CDN hasn’t been upgraded in years.
This is where Automatic SSL/TLS sits in the story of how we secure Internet communications.
Automatic SSL/TLS
Automatic SSL/TLS grew out of Cloudflare’s mission to ensure the web was as encrypted as possible. While we had initially spent an incredibly long time developing secure connections for the “front door” (from browsers to Cloudflare’s edge) with Universal SSL, we knew that the “back door” (from Cloudflare’s edge to origin servers) would be slower and harder to upgrade.
One option we offered was Cloudflare Tunnel, where a lightweight agent runs near the origin server and tunnels traffic securely back to Cloudflare. This approach ensures the connection always uses modern encryption, without requiring changes on the origin itself.
But not every customer uses Tunnel. Many connect origins directly to Cloudflare’s edge, where encryption depends on the origin server’s configuration. Traditionally this meant customers had to either manually select an encryption mode that worked for their origin server or rely on the default chosen by Cloudflare.
To improve the experience of choosing an encryption mode, we introduced our SSL/TLS Recommender in 2021.
The Recommender scanned customer origin servers and then provided recommendations for their most secure encryption mode. For example, if the Recommender detected that an origin server was using a certificate signed by a trusted Certificate Authority (CA) such as Let’s Encrypt, rather than a self-signed certificate, it would recommend upgrading from Full encryption mode to Full (Strict) encryption mode.
Based on how the origin responded, Recommender would tell customers if they could improve their SSL/TLS encryption mode to be more secure. The following encryption modes represent what the SSL/TLS Recommender could recommend to customers based on their origin responses:
However, in the three years after launching our Recommender we discovered something troubling: of the over two million domains using Recommender, only 30% of the recommendations that the system provided were followed. A significant number of users would not complete the next step of pushing the button to inform Cloudflare that we could communicate with their origin over a more secure setting.
We were seeing sub-optimal settings that our customers could upgrade from without risk of breaking their site, but for various reasons, our users did not follow through with the recommendations. So we pushed forward by building a system that worked with Recommender and actioned the recommendations by default.
How does Automatic SSL/TLS work?
Automatic SSL/TLSworks by crawling websites, looking for content over both HTTP and HTTPS, then comparing the results for compatibility. It also performs checks against the TLS certificate presented by the origin and looks at the type of content that is served to ensure it matches. If the downloaded content matches, Automatic SSL/TLS elevates the encryption level for the domain to the compatible and stronger mode, without risk of breaking the site.
More specifically, these are the steps that Automatic SSL/TLS takes to upgrade domain’s security:
Each domain is scheduled for a scan once per month (or until it reaches the maximum supported encryption mode).
The scan evaluates the current encryption mode for the domain. If it’s lower than what the Recommender thinks the domain can support based on the results of its probes and content scans, the system begins a gradual upgrade.
Automatic SSL/TLS begins to upgrade the domain by connecting with origins over the more secure mode starting with just 1% of its traffic.
If connections to the origin succeed, the result is logged as successful.
If they fail, the system records the failure to Cloudflare’s control plane and aborts the upgrade. Traffic is immediately downgraded back to the previous SSL/TLS setting to ensure seamless operation.
If no issues are found, the new SSL/TLS encryption mode is applied to traffic in 10% increments until 100% of traffic uses the recommended mode.
Once 100% of traffic has been successfully upgraded with no TLS-related errors, the domain’s SSL/TLS setting is permanently updated.
Special handling for Flexible → Full/Strict: These upgrades are more cautious because customers’ cache keys are changed (from http to https origin scheme).
In this situation, traffic ramps up from 1% to 10% in 1% increments, allowing customers’ cache to warm-up.
After 10%, the system resumes the standard 10% increments until 100%.
We know that transparency and visibility are critical, especially when automated systems make changes. To keep customers informed, Automatic SSL/TLS sends a weekly digest to account Super Administrators whenever updates are made to domain encryption modes. This way, you always have visibility into what changed and when.
In short, Automatic SSL/TLS automates what used to be trial and error: finding the strongest SSL/TLS mode your site can support while keeping everything working smoothly.
How are we doing so far?
So far we have onboarded all Free, Pro, and Business domains to use Automatic SSL/TLS. We also have enabled this for all new domains that will onboard onto Cloudflare regardless of plantype. Soon, we will start onboarding Enterprise customers as well. If you already have an Enterprise domain and want to try out Automatic SSL/TLS we encourage you to enable it in the SSL/TLS section of the dashboard or via the API.
As of the publishing of this blog, we’ve upgraded over 6 million domains to be more secure without the website operators needing to manually configure anything on Cloudflare.
Previous Encryption Mode
Upgraded Encryption Mode
Number of domains
Flexible
Full
~ 2,200,000
Flexible
Full (strict)
~ 2,000,000
Full
Full (strict)
~ 1,800,000
Off
Full
~ 7,000
Off
Full (strict)
~ 5,000
We’re most excited about the over 4 million domains that moved from Flexible or Off, which uses HTTP to origin servers, to Full or Strict, which uses HTTPS.
If you have a reason to use a particular encryption mode (e.g., on a test domain that isn’t production ready) you can always disable Automatic SSL/TLS and manually set the encryption mode that works best for your use case.
Today, SSL/TLS mode works on a domain-wide level, which can feel blunt. This means that one suboptimal subdomain can keep the entire domain in a less secure TLS setting, to ensure availability. Our long-term goal is to make these controls more precise, so that Automatic SSL/TLS and encryption modes can optimize security per origin or subdomain, rather than treating every hostname the same.
Impact on origin-facing connections
Since we began onboarding domains to Automatic SSL/TLS in late 2024 and early 2025, we’ve been able to measure how origin connections across our network are shifting toward stronger security. Looking at the ratios across all origin requests, the trends are clear:
Encryption is rising. Plaintext connections are steadily declining, a reflection of Automatic SSL/TLS helping millions of domains move to HTTPS by default. We’ve seen a correlated 7-8% reduction in plaintext origin-bound connections. Still, some origins remain on outdated configurations, and these should be upgraded to keep pace with modern security expectations.
TLS 1.3 is surging. Since late 2024, TLS 1.3 adoption has climbed sharply, now making up the majority of encrypted origin traffic (almost 60%). While Automatic SSL/TLS doesn’t control which TLS version an origin supports, this shift is an encouraging sign for both performance and security.
Older versions are fading. Month after month, TLS 1.2 continues to shrink, while TLS 1.0 and 1.1 are now so rare they barely register.
The decline in plaintext connections is encouraging, but it also highlights a long tail of servers still relying on outdated packages or configurations. Sites like SSL Labs can be used, for instance, to check a server’s TLS configuration. However, simply copy-pasting settings to achieve a high rating can be risky, so we encourage customers to review their origin TLS configurations carefully. In addition, Cloudflare origin CA or Cloudflare Tunnel can help provide guidance for upgrading origin security.
Upgraded domain results
Instead of focusing on the entire network of origin-facing connections from Cloudflare, we’re now going to drill into specific changes that we’ve seen from domains that have been upgraded by Automatic SSL/TLS.
By January 2025, most domains had been enrolled in Automatic SSL/TLS, and the results were dramatic: a near 180-degree shift from plaintext to encrypted communication with origins. After that milestone, traffic patterns leveled off into a steady plateau, reflecting a more stable baseline of secure connections across the network. There is some drop in encrypted traffic which may represent some of the originally upgraded domains manually turning off Automatic SSL/TLS.
But the story doesn’t end there. In the past two months (July and August 2025), we’ve observed another noticeable uptick in encrypted origin traffic. This likely reflects customers upgrading outdated origin packages and enabling stronger TLS support—evidence that Automatic SSL/TLS not only raised the floor on encryption but continues nudging the long tail of domains toward better security.
To further explore the “encrypted” line above, we wanted to see what the delta was between TLS 1.2 and 1.3. Originally we wanted to include all TLS versions we support but the levels of 1.0 and 1.1 were so small that they skewed the graph and were taken out. We see a noticeable rise in the support for both TLS 1.2 and 1.3 between Cloudflare and origin servers. What is also interesting to note here is the network-wide decrease in TLS 1.2 but for the domains that have been automatically upgraded a generalized increase, potentially also signifying origin TLS stacks that could be updated further.
Finally, for Full (Strict) mode,we wanted to investigate the number of successful certificate validations we performed. This line shows a dramatic, approximately 40%, increase in successful certificate validations performed for customers upgraded by Automatic SSL/TLS.
We’ve seen a largely successful rollout of Automatic SSL/TLS so far, with millions of domains upgraded to stronger encryption by default. We’ve seen help Automatic SSL/TLS improve origin-facing security, safely pushing connections to stronger modes whenever possible, without risking site breakage. Looking ahead, we’ll continue to expand this capability to more customer use cases as we help to build a more encrypted Internet.
What will we build next for Automatic SSL/TLS?
We’re expanding Automatic SSL/TLS with new features that give customers more visibility and control, while keeping the system safe by default. First, we’re building an ad-hoc scan option that lets you rescan your origin earlier than the standard monthly cadence. This means if you’ve just rotated certificates, upgraded your origin’s TLS configuration, or otherwise changed how your server handles encryption, you won’t need to wait for the next scheduled pass—Cloudflare will be able to re-evaluate and move you to a stronger mode right away.
In addition, we’re working on error surfacing that will highlight origin connection problems directly in the dashboard and provide actionable guidance for remediation. Instead of discovering after the fact that an upgrade failed, or a change on the origin resulted in a less secure setting than what was set previously, customers will be able to see where the issue lies and how to fix it.
Finally, for newly onboarded domains, we plan to add clearer guidance on when to finish configuring the origin before Cloudflare runs its first scan and sets an encryption mode. Together, these improvements are designed to reduce surprises, give customers more agency, and ensure smoother upgrades. We expect all three features to roll out by June 2026.
Post Quantum Era
Looking ahead, quantum computers introduce a serious risk: data encrypted today can be harvested and decrypted years later once quantum attacks become practical. To counter this harvest-now, decrypt-later threat, the industry is moving towards post-quantum cryptography (PQC)—algorithms designed to withstand quantum attacks. We have extensively written on this subject in our previous blogs.
In August 2024, NIST finalized its PQC standards: ML-KEM for key agreement, and ML-DSA and SLH-DSA for digital signatures. In collaboration with industry partners, Cloudflare has helped drive the development and deployment of PQC. We have deployed the hybrid key agreement, combining ML-KEM (post-quantum secure) and X25519 (classical), to secure TLS 1.3 traffic to our servers and internal systems. As of mid-September 2025, around 43% of human-generated connections to Cloudflare are already protected with the hybrid post-quantum secure key agreement – a huge milestone in preparing the Internet for the quantum era.
But things look different on the other side of the network. When Cloudflare connects to origins, we act as the client, navigating a fragmented landscape of hosting providers, software stacks, and middleboxes. Each origin may support a different set of cryptographic features, and not all are ready for hybrid post-quantum handshakes.
To manage this diversity without the risk of breaking connections, we relied on HelloRetryRequest. Instead of sending post-quantum keyshare immediately in the ClientHello, we only advertise support for it. If the origin server supports the post-quantum key agreement, it uses HelloRetryRequest to request it from Cloudflare, and creates the post-quantum connection. The downside is this extra round trip (from the retry) cancels out the performance gains of TLS 1.3 and makes the connection feel closer to TLS 1.2 for uncached requests.
Back in 2023, we launched an API endpoint, so customers could manually opt their origins into preferring post-quantum connections. If set, we avoid the extra roundtrip and try to create a post-quantum connection at the start of the TLS session. Similarly, we extended post-quantum protection to Cloudflare tunnel, making it one of the easiest ways to get origin-facing PQ today.
Starting Q4 2025, we’re taking the next step – making it automatic. Just as we’ve done with SSL/TLS upgrades, Automatic SSL/TLS will begin testing, ramping, and enabling post-quantum handshakes with origins—without requiring customers to change a thing, as long as their origins support post-quantum key agreement.
Behind the scenes, we’re already scanning active origins about every 24 hours to test support and preferences for both classical and post-quantum key agreements. We’ve worked directly with vendors and customers to identify compatibility issues, and this new scanning system will be fully integrated into Automatic SSL/TLS.
And the benefits won’t stop at post-quantum. Even for classical handshakes, optimization matters. Today, the X25519 algorithm is used by default, but our scanning data shows that more than 6% of origins currently prefer a different key agreement algorithm, which leads to unnecessary HelloRetryRequests and wasted round trips. By folding this scanning data into Automatic SSL/TLS, we’ll improve connection establishment for classical TLS as well—squeezing out extra speed and reliability across the board.
As enterprises and hosting providers adopt PQC, our preliminary scanning pipeline has already found that around 4% of origins could benefit from a post-quantum-preferred key agreement even today, as shown below. This is an 8x increase since we started our scans in 2023. We expect this number to grow at a steady pace as the industry continues to migrate to post-quantum protocols.
As part of this change, we will also phase out support for the pre-standard version X25519Kyber768 to support the final ML-KEM standard, again using a hybrid, from edge to origin connections.
With Automatic SSL/TLS, we will soon by default scan your origins proactively to directly send the most preferred keyshare to your origin removing the need for any extra roundtrip, improving both security and performance of your origin connections collectively.
At Cloudflare, we’ve always believed security is a right, not a privilege. From Universal SSL to post-quantum cryptography, our mission has been to make the strongest protections free and available to everyone. Automatic SSL/TLS is the next step—upgrading every domain to the best protocols automatically. Check the SSL/TLS section of your dashboard to ensure it’s enabled and join the millions of sites already secured for today and ready for tomorrow.
Three Dutch security analysts discovered the vulnerabilities—five in total—in a European radio standard called TETRA (Terrestrial Trunked Radio), which is used in radios made by Motorola, Damm, Hytera, and others. The standard has been used in radios since the ’90s, but the flaws remained unknown because encryption algorithms used in TETRA were kept secret until now.
In 2023, Carlo Meijer, Wouter Bokslag, and Jos Wetzels of security firm Midnight Blue, based in the Netherlands, discovered vulnerabilities in encryption algorithms that are part of a European radio standard created by ETSI called TETRA (Terrestrial Trunked Radio), which has been baked into radio systems made by Motorola, Damm, Sepura, and others since the ’90s. The flaws remained unknown publicly until their disclosure, because ETSI refused for decades to let anyone examine the proprietary algorithms.
[…]
But now the same researchers have found that at least one implementation of the end-to-end encryption solution endorsed by ETSI has a similar issue that makes it equally vulnerable to eavesdropping. The encryption algorithm used for the device they examined starts with a 128-bit key, but this gets compressed to 56 bits before it encrypts traffic, making it easier to crack. It’s not clear who is using this implementation of the end-to-end encryption algorithm, nor if anyone using devices with the end-to-end encryption is aware of the security vulnerability in them.
[…]
The end-to-end encryption the researchers examined recently is designed to run on top of TETRA encryption algorithms.
The researchers found the issue with the end-to-end encryption (E2EE) only after extracting and reverse-engineering the E2EE algorithm used in a radio made by Sepura.
These seem to be deliberately implemented backdoors.
The auction, which will include other items related to cryptology, will be held Nov. 20. RR Auction, the company arranging the sale, estimates a winning bid between $300,000 and $500,000.
Along with the original handwritten plain text of K4 and other papers related to the coding, Mr. Sanborn will also be providing a 12-by-18-inch copper plate that has three lines of alphabetic characters cut through with a jigsaw, which he calls “my proof-of-concept piece” and which he kept on a table for inspiration during the two years he and helpers hand-cut the letters for the project. The process was grueling, exacting and nerve wracking. “You could not make any mistake with 1,800 letters,” he said. “It could not be repaired.”
Mr. Sanborn’s ideal winning bidder is someone who will hold on to that secret. He also hopes that person is willing to take over the system of verifying possible solutions and reviewing those unending emails, possibly through an automated system.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.