AWS completes CCAG 2022 pooled audit by European FSI customers

Post Syndicated from Manuel Mazarredo original https://aws.amazon.com/blogs/security/aws-completes-ccag-2022-pooled-audit-by-european-fsi-customers/

We are excited to announce that Amazon Web Services (AWS) has completed its annual Collaborative Cloud Audit Group (CCAG) Cloud Community audit with European financial service institutions (FSIs).

Security at AWS is the highest priority. As customers embrace the scalability and flexibility of AWS, we are helping them evolve security, identity, and compliance into key business enablers. At AWS, we are obsessed with earning and maintaining customer trust, and providing our FSI customers and their regulatory bodies with the assurance that AWS has the necessary controls in place to protect their most sensitive material and regulated workloads. The AWS Compliance Program helps customers understand the robust controls that are in place at AWS. By tying together governance-focused, audit-friendly service features with applicable compliance or audit standards, AWS Compliance helps customers to set up and operate in an AWS security control environment.

An example of how AWS supports customers’ risk management and regulatory efforts is our annual audit engagement with the CCAG. For the fourth year, the CCAG pooled audit thoroughly assessed the AWS controls that enable us to help protect our customers’ data and material workloads, while satisfying strict European and national regulatory obligations. CCAG currently represents more than 50 leading European FSIs and has grown steadily since its inception in 2017. Given the importance of cloud computing for the operations of FSI customers, the financial industry is coming under greater regulatory scrutiny. Similar to prior years, the CCAG 2022 audit was conducted based on customers’ right to conduct an audit of their service providers under European Banking Authority (EBA) outsourcing recommendations to cloud service providers (CSPs). The EBA suggests using pooled audits to use audit resources more efficiently and to decrease the organizational burden on both the clients and the CSP. Figure 1 illustrates the improved cost-effectiveness of pooled audits as compared to individual audits.

Figure 1: Efforts and costs are shared and reduced when a collaborative approach is followed

Figure 1: Efforts and costs are shared and reduced when a collaborative approach is followed

CCAG audit process

Although there are many security frameworks available, CCAG uses the Cloud Controls Matrix (CCM) of the Cloud Security Alliance (CSA) as the framework of reference for their CSP audits. The CSA is a not-for-profit organization with a mission, as stated on its website, to “promote the use of best practices for providing security assurance within cloud computing, and to provide education on the uses of cloud computing to help secure all other forms of computing.” CCM is specifically designed to provide fundamental security principles to guide cloud vendors and to assist cloud customers in assessing the overall security risk of a cloud provider.

Between February and December 2022, CCAG audited the AWS controls environment by following a hybrid approach, remotely and onsite in Seattle (USA), Dublin (IRL), and Frankfurt (DEU). For the scope of the 2022 CCAG audit, the participating auditors assessed AWS measures with regards to (1) keeping customer data sovereign, secure, and private, (2) effectively managing threats and vulnerabilities, (3) offering a highly available and resilient infrastructure, (4) preventing and responding rapidly to security events, and (5) enforcing strong authentication mechanisms and strict identity and access management constraint conditions to grant access to resources only under the need-to-know and need-to-have principles.

The scope of the audit encompassed individual services provided by AWS, and the policies, controls, and procedures for (and practice of) managing and maintaining them. Customers will still need to have their auditors assess the environments they create by using these services, and their policies and procedures for (and practices of) managing and maintaining these environments, on their side of the shared responsibility lines of demarcation for the AWS services involved.

CCAG audit results

CCAG members expressed their gratitude to AWS for the audit experience:

“The AWS Security Assurance team provided CCAG auditors with the needed logistical and technical assistance, by navigating the AWS organization to find the required information, performing advocacy of the CCAG audit rights, creating awareness and education, as well as exercising constant pressure for the timely delivery of information.”

The results of the CCAG pooled audit are available to the participants and their respective regulators only, and provide CCAG members with assurance regarding the AWS controls environment, enabling members to work to remove compliance blockers, accelerate their adoption of AWS services, and obtain confidence and trust in the security controls of AWS.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Want more AWS Security news? Follow us on Twitter.

Manuel Mazarredo

Manuel Mazarredo

Manuel is a security audit program manager at AWS based in Amsterdam, the Netherlands. Manuel leads security audits, attestations, and certification programs across Europe, and is responsible for the BeNeLux area. For the past 18 years, he has worked in information systems audits, ethical hacking, project management, quality assurance, and vendor management across a variety of industries.

Andreas Terwellen

Andreas Terwellen

Andreas is a senior manager in security audit assurance at AWS, based in Frankfurt, Germany. His team is responsible for third-party and customer audits, attestations, certifications, and assessments across Europe. Previously, he was a CISO in a DAX-listed telecommunications company in Germany. He also worked for different consulting companies managing large teams and programs across multiple industries and sectors.

Julian Herlinghaus

Julian Herlinghaus

Julian is a Manager in AWS Security Assurance based in Berlin, Germany. He leads third-party and customer security audits across Europe and specifically the DACH region. He has previously worked as Information Security department lead of an accredited certification body and has multiple years of experience in information security and security assurance & compliance.

Author Spotlight: Eduardo Monich Fronza, Senior Partner Solutions Architect, Linux and IBM

Post Syndicated from Elise Chahine original https://aws.amazon.com/blogs/architecture/author-spotlight-eduardo-monich-fronza-senior-partner-sa-linux-and-ibm/

The Author Spotlight series pulls back the curtain on some of AWS’s most prolific authors. Read on to find out more about our very own Eduardo Monich Fronza’s journey, in his own words!


I have been a Partner Solutions Architect at Amazon Web Services (AWS) for just over two years. In this period, I have had the opportunity to work in projects from different partners and customers across the globe, in multiple industry segments, using a wide variety of technologies.

At AWS, we are obsessed with our customers, and this influences all of our activities. I enjoy diving deep to understand our partners’ motivations, as well as their technical and business challenges. Plus, I work backwards from their goals, helping them build innovative solutions using AWS services—solutions that they can successfully offer to their customers and achieve their targeted business results.

Before joining AWS, I worked mainly in Brazil for many years as a middleware engineer and, later, a cloud migration architect. During this period, I travelled to my customers in North America and Europe. These experiences taught me a lot about customer-facing engagements, how to focus on customers problems, and how to work backwards from those.

When I joined AWS, I was exposed to so many new technologies and projects that I have never had any previous experience with! This was a very exciting, as it provided me with many opportunities to dive deep and learn. A couple of the places I love to go to learn new content are our AWS Architecture Blog and AWS Reference Architecture Diagrams library.

The other thing I’ve realized during my tenure is how amazing it is to work with other people at AWS. I can say that I feel very fortunate to work with a wide range of intelligent and passionate problem-solvers. My peers are always willing to help and work together to provide the best possible solutions for our partners. I believe this collaboration is one of the reasons why AWS has been able to help partners and customer be so successful in their journeys to the cloud.

AWS encourages us to dive deep and specialize in technology domains. My background as a middleware engineer has influenced my decisions, and I am passionate about application modernization and containers areas in particular. A couple of topics that I am particularly interested in are Red Hat OpenShift Service on AWS (ROSA) and IBM software on AWS.

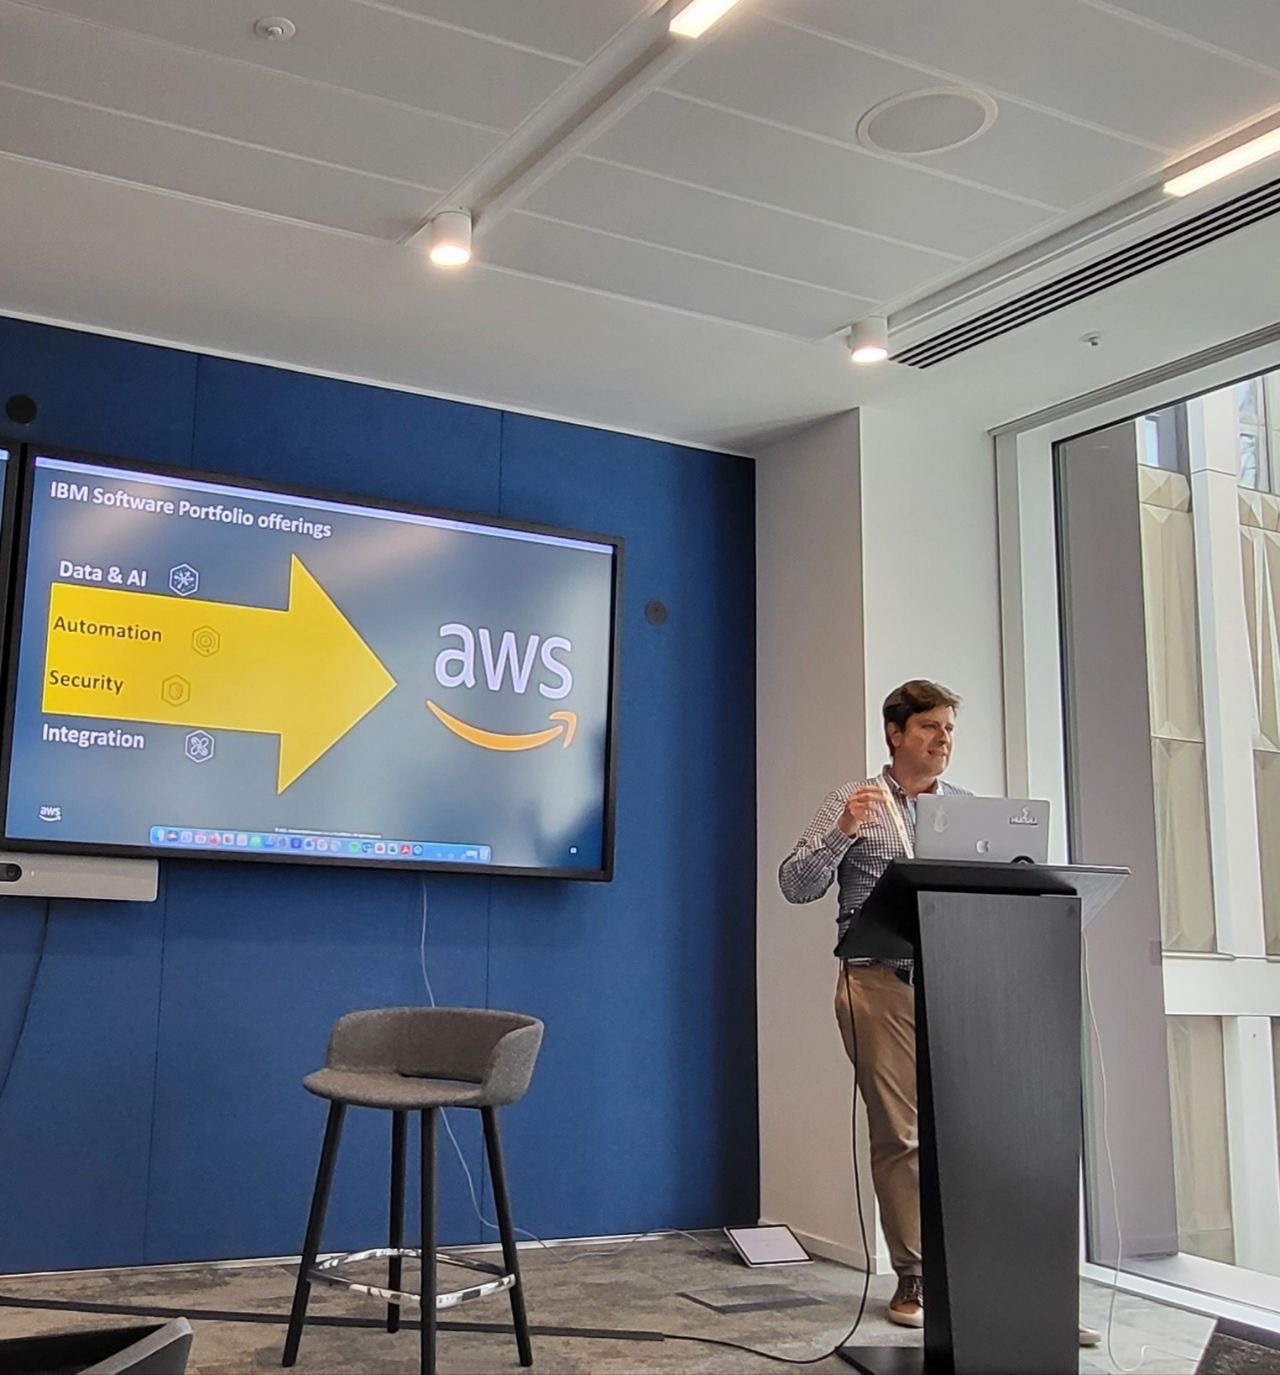
Eduardo presenting on the strategic partnership between AWS and IBM at IBM Think London 2022

Eduardo presenting on the strategic partnership between AWS and IBM at IBM Think London 2022

This also shows how interesting it is to work with ISVs like Red Hat and IBM. It demonstrates, yet again, how AWS is customer-obsessed and works backwards from what customers need to be successful in their own rights. Regardless of if they are using AWS native services or an ISV solution on AWS, we at AWS always focus on what is right for our customers.

I am also very fond of running workshops, called Immersion Days, for our customers. And, I have recently co-authored an AWS modernization workshop with IBM, which shows how customers can use IBM Cloud Pak for Data on AWS along with AWS services to create exciting Analytics and AI/ML workloads!

In conclusion, working as a Partner Solutions Architect at AWS has been an incredibly rewarding experience for me. I work with great people, a wide range of industries and technologies, and, most importantly, help our customers and partners innovate and find success on AWS. If you are considering a career at AWS, I would highly recommend it: it’s an unparalleled working experience, and the are no shortages of opportunities to take part in exciting projects!

Eduardo’s favorite blog posts!

Deploying IBM Cloud Pak for Data on Red Hat OpenShift Service on AWS

Alright, I will admit: I am being a bit biased. But, hey, this was my first blog at AWS! Many customers are looking to adopt IBM Data and AI solutions on AWS, particularly on how to use ROSA to deploy IBM Cloud Pak for Data.

So, I created a how-to deployment guide, demonstrating how a customer can take advantage of ROSA, without having to manage the lifecycle of Red Hat OpenShift Container Platform clusters. Instead, I focus on developing new solutions and innovating faster, using IBM’s integrated data and artificial intelligence platform on AWS.

IBM Cloud Pak for Integration on ROSA architecture

IBM Cloud Pak for Integration on ROSA architecture

Unleash Mainframe Applications by Augmenting New Channels on AWS with IBM Z and Cloud Modernization Stack

Many AWS customers use the IBM mainframe for their core business-critical applications. These customers are looking for ways to build modern cloud-native applications on AWS, that often require access to business-critical data on their IBM mainframe.

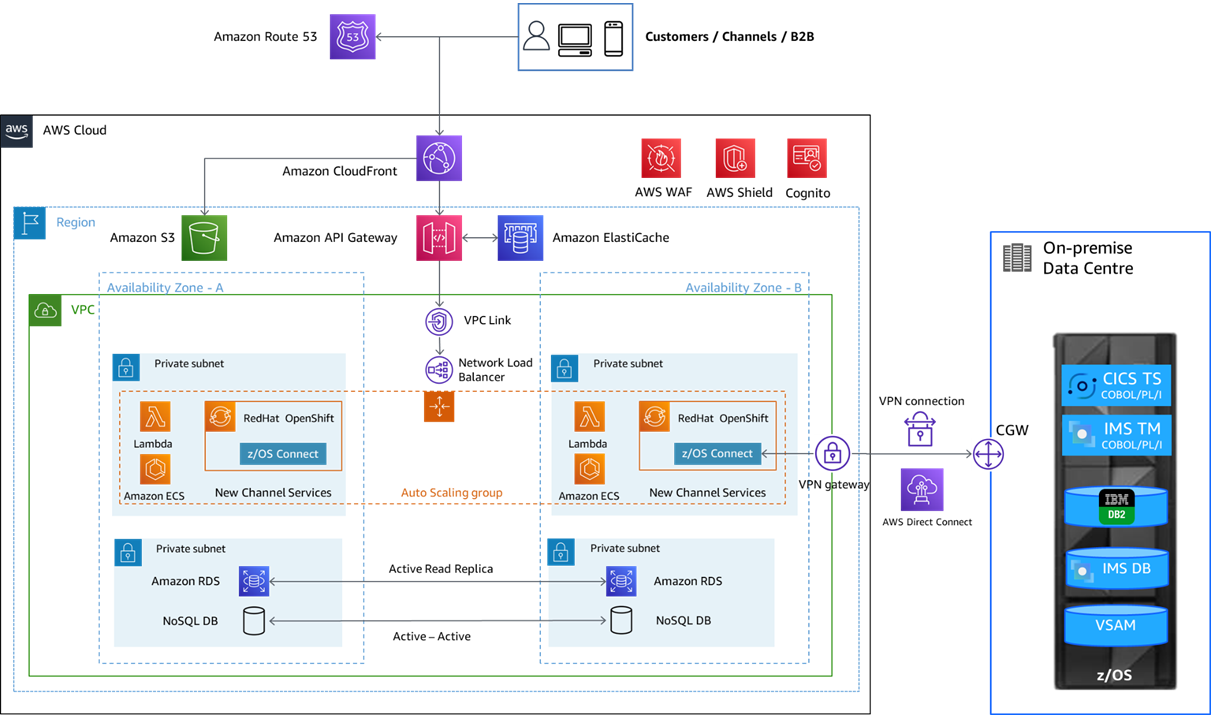
This AWS Partner Network (APN) Blog post shows how these customers can integrate cloud-native applications on AWS, with workloads running on mainframes, by exposing them as industry standard RESTful APIs with a no-code approach.

Mainframe-to-AWS integration reference architecture.

Mainframe-to-AWS integration reference architecture.

Migrate and Modernize Db2 Databases to Amazon EKS Using IBM’s Click to Containerize Tool

This blog shows customers, who are exploring ways to modernize their IBM Db2 databases, can move their databases quickly and easily to Amazon Elastic Kubernetes Service (Amazon EKS), ROSA and IBM’s Cloud Pak for Data products on AWS.

Scenario showing move from instance to container

Scenario showing move from instance to container

Self-service AWS native service adoption in OpenShift using ACK

This Containers Blog post demonstrates how customers can use AWS Controllers for Kubernetes (ACK) to define and create AWS resources directly from within OpenShift. It allows customers to take advantage of AWS-managed services to complement the application workloads running in OpenShift, without needing to define resources outside of the cluster or run services that provide supporting capabilities like databases or message queues.

ACK is now integrated into OpenShift and being used to provide a broad collection of AWS native services presently available on the OpenShift OperatorHub.

AWS Controllers for Kubernetes workflow

AWS Controllers for Kubernetes workflow

Thinking Through Your Cloud Strategy With Veeam’s V12 Release

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/thinking-through-your-cloud-strategy-with-veeams-v12-release/

We wouldn’t normally make a big deal about another company’s version release except this one is, well… kind of a big deal. Unlike most software releases that fly under the radar, there are big implications—for your backup strategy, your cloud storage usage, and your budget.

Leading backup and recovery provider, Veeam, announced the release of Version 12 (v12) of its popular Backup & Replication software on February 14. And we’re feeling the backup love.

So, what’s the big deal? With this release, Veeam customers can send backups directly to the cloud instead of (or in addition to) routing them to local storage first. Ultimately, the changes announced in v12 provide for easier backups, more diversified workloads, more flexibility in your cloud strategy, and capital expense (CapEx) savings on local storage.

Today, we’re breaking down what all that means and how you can take advantage of the changes to optimize your backup strategy and cloud storage spend.

Save the Date for VeeamON 2023 May 22–24 in Miami

Learn more about the Veeam v12 release and how Backblaze and Veeam make modern data protection easy. Backblaze is proud to be a Platinum sponsor at VeeamON this year and we look forward to seeing you there!

About Veeam

Veeam is a leader in backup, recovery, and data management solutions. They offer a single platform for cloud, virtual, physical, software as a service (SaaS), and Kubernetes environments. Their products help customers own, control, and protect data anywhere in the hybrid cloud.

Customers can already select Backblaze B2 Cloud Storage as a destination for their Veeam backups, and doing so just got a whole lot easier with v12. Read on to learn more.

How Veeam Previously Worked with Cloud Storage

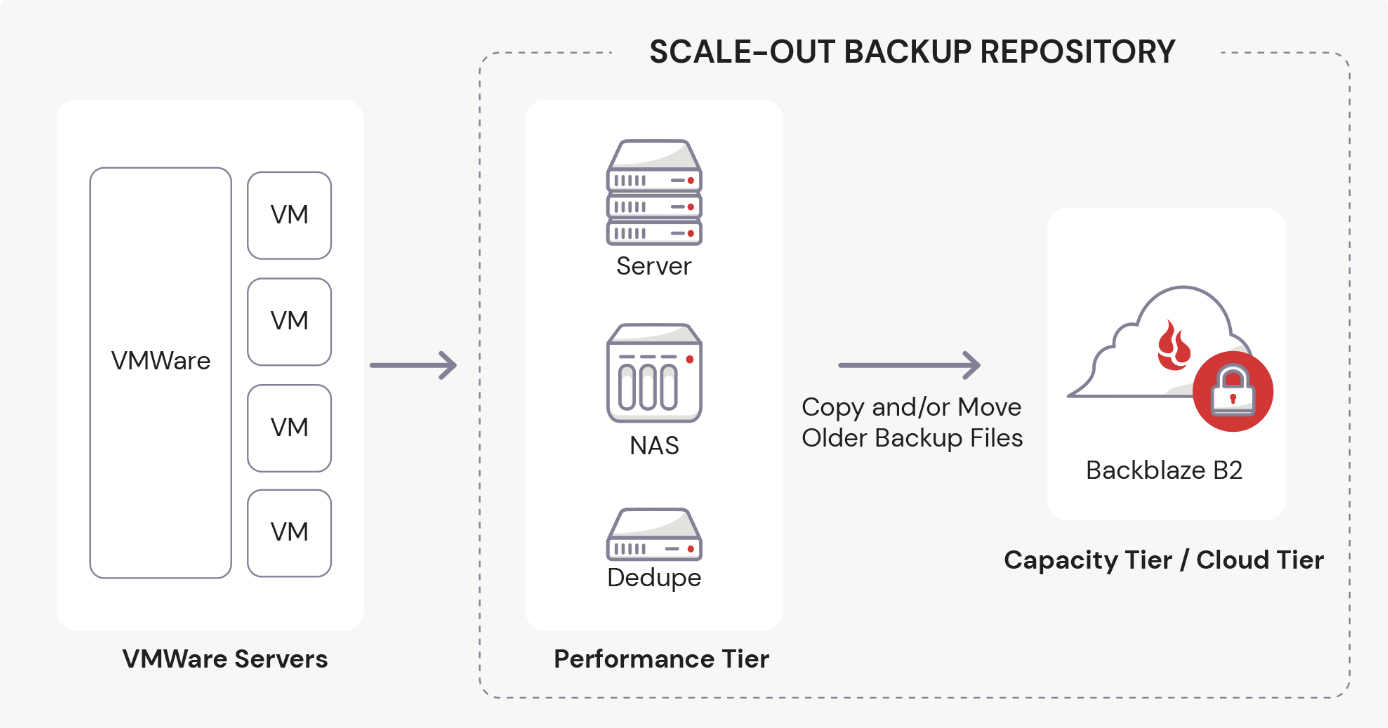
Prior to v12, cloud object storage was enabled in Veeam through the Scale-Out Backup Repository (SOBR). To set up the Cloud Tier, you first had to set up a local repository for your backup data. Many people used a NAS for this purpose, but it could also be a SAN, hard drives, etc. This was your primary repository, also known as your performance tier.

Here’s an example workflow with SOBR and Backblaze B2.

You needed enough capacity on your local repository to land the data there first before you could then use the Veeam console to Move or Copy it to the cloud. If your data set is perpetually growing (and whose isn’t?), you previously had to either tier off more data to the cloud to free up local capacity, or invest in more local storage.

Veeam v12 changes all that.

Veeam v12 Gives You Choices

With this new version release, the primary repository can now be local, on-premises storage, or it can also be local object storage arrays or cloud storage like Backblaze B2.

You can still use the SOBR or back up direct to object storage. This opens up a whole range of benefits, including:

  • Easier Backups: You can now use the Backup Job functionality to send your data straight to the cloud. You no longer need to land it in local storage first. You can also create multiple Backup Jobs that go to different destinations. For instance, to better fortify your backup strategy, you can create a Backup Job to a Backblaze B2 Bucket in one region and then a Backup Copy Job to a B2 Bucket in a different region for redundancy purposes.
  • Diversified Workloads: More choices give you the ability to think through your workloads and how you want to optimize them for cost and access. You may want to send less critical workloads—like older backups, archives, or data from less important work streams—to the cloud to free up capacity on your local storage. You can do this by editing your Backup Jobs (using the Move backup function) that were previously routing through the SOBR to cloud storage to point directly to cloud object storage instead.
  • More Flexibility: v12 allows for more flexibility to use cloud storage in your backup strategy. You have options, including:
    • Making your primary repository on-premises and using the cloud as part of your Capacity Tier in the SOBR.
    • Moving to a fully cloud-based repository.
    • Mixing your use of the SOBR and direct-to-object storage Backup Jobs to optimize your disaster recovery (DR) strategy, recovery needs, and costs.
  • CapEx Savings: You no longer need to keep investing in more local storage as your data set grows. Rather than buying another server or NAS, you can optimize your existing infrastructure by more easily off-loading data to cloud storage to free up capacity on on-premises devices.

What’s Next: Thinking Through Your Strategy

Great, you have more choices. But which choice should you make, and why?

Ultimately, you want to increase your company’s cyber resilience. Your backup strategy should be airtight, but you also need to think through your recovery process and your DR strategy as well. We’ll explain a couple different ways you could make use of the functionality v12 provides and break down the pros and cons of each.

Scenario 1: Using Cloud Storage as Part of Your SOBR

In this case, your on-premises storage is your primary repository and the cloud is your secondary repository. The advantage of an on-premises repository is that it’s often going to give you the fastest, easiest access to recovery. If your recovery time objective (RTO) is very short, a local backup is likely going to give you the fastest data restoration option to meet that RTO goal.

Then, copy your backups to cloud storage to ensure you have another copy in case of a local disaster. This is always good practice as part of the 3-2-1 rule or 3-2-1-1-0 rule. Why is it important to have a copy in cloud storage? Well, even if you store backups for disaster recovery at another location, is your DR site far away enough? Is it immune from a local disaster? If not, you need another copy in the cloud in a location that’s geographically distanced from you.

Scenario 2: Using the Cloud as Your Primary Repository

In this case, the cloud is your primary repository. Direct backups to cloud object storage from Veeam are helpful for the following use cases:

  • Less critical workloads: This could include a lesser-used server, archived projects, files, and data; or business data that is less critical to restore in the case of disaster recovery.
  • To free up local storage: If you’re running up against a lack of local storage and need to make a decision on spending more for additional on-premises storage, the cloud is often more affordable than investing in additional physical storage devices.
  • Workloads where slightly longer recovery periods are acceptable: If you can handle a slightly longer recovery period, cloud storage is a good fit. But remember that not all cloud storage is created equal. Backblaze B2, for example, is always-hot storage, so you won’t have to worry about cold storage delays like you might with AWS Glacier.
  • To migrate away from an LTO system: If you were previously sending backup copy jobs to tape, you can now more easily use cloud storage as a replacement.
  • To eliminate a secondary on-premises location: Maybe you are worried your backups are stored too close to each other, or you simply want to get rid of a secondary on-premises location. The direct-to-cloud option gives you this option. You can reroute those backup copy jobs to copy direct-to-cloud object storage instead.
  • To eliminate on-premises backups altogether: Of course, if you want to completely eliminate local backups for whatever reason, you can now do that by sending all your backup and archive data to the cloud only, although you should carefully consider the implications of that strategy for your disaster recovery plan.

Planning for Disaster Recovery—How You’ll Restore

While it’s important to think about how to optimize your backup strategy using the new functionality introduced by v12, it’s equally as important to think about how you’ll restore business operations in the case of an on-premises disaster. Backblaze offers a unique solution through its partnerships with Veeam and PhoenixNAP—Instant Recovery in Any Cloud.

With this solution, you can run a single command using an industry-standard automation tool to quickly bring up an orchestrated combination of on-demand servers, firewalls, networking, storage, and other infrastructure in phoenixNAP. The command draws data from Veeam backups immediately to your VMware/Hyper-V based environment, so businesses can get back online with minimal disruption or expense. Best of all, there’s no cost unless you actually need to use the solution, so there’s no reason not to set it up now.

Instant Recovery in Any Cloud works with both of the scenarios described above—whether your cloud is your primary or secondary repository. One advantage of using the direct-to-cloud object storage Backup Job is that you can more easily leverage Instant Recovery in Any Cloud since your primary backup is in the cloud. Taking advantage of cloud transit speeds, your business can get back up and running in less time than it would take to restore back to on-premises storage.

Planning for Disaster Recovery—How You’ll Budget

Another consideration for tightening up your cyber resilience plan (and getting your executive team on board with it) is better understanding and anticipating any egress expenses you may face when recovering data—because the last thing you want to be doing in the case of a major data disaster is trying to convince your executive team to sign off on an astronomical egress bill from your cloud provider.

At Backblaze, we’ve always believed it’s good and right to enable customers to readily use their data. With B2 Reserve, our capacity-based offering, there are no egress fees, unlike those charged by AWS, Azure, and Google Cloud. B2 Reserve also includes premium support and Universal Data Migration services so you can move your data from another cloud provider without any lift on your team’s part.

For our Backblaze B2 pay-as-you-go consumption-based offering, egress fees stand at just $0.01/GB, and we waive egress fees altogether with many of our compute and CDN partners.

How Veeam Works with Backblaze B2

Backblaze is a Veeam Ready partner and certified Veeam Ready for Object with Immutability, meaning it’s incredibly easy to set up Backblaze B2 Cloud Storage as your cloud repository in Veeam’s SOBR. In fact, it takes only about 20 minutes.

Setting up Backblaze B2 as your primary repository in the direct-to-object storage method is even easier. Just follow the steps in our Quick-Start Guide to get started.

Backblaze B2 is one-fifth the cost of other major cloud providers and offers enterprise-grade security without enterprise pricing. Unlike other cloud providers, we do not charge extra for the use of Object Lock, which enables immutability for protection from ransomware. There’s also no minimum retention requirement unlike other cloud providers who charge you for 30, 60 or even 90 days for deleted data.

No matter how you choose to configure Veeam with Backblaze B2, you’ll know that your data is protected from on-site disaster, ransomware, and hardware failure.

Veeam + Backblaze: Now Even Easier

Get started today for $5/TB per month or contact your favorite reseller, like CDW or SHI, to purchase Backblaze via B2 Reserve, our all-inclusive capacity-based bundles.

The post Thinking Through Your Cloud Strategy With Veeam’s V12 Release appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

[$] Rethinking splice()

Post Syndicated from original https://lwn.net/Articles/923237/

The splice()
system call
is built on an appealing idea: connect two file descriptors
together so that data can be moved from one to the other without passing
through user space and, preferably, without being copied in the kernel.
splice() has enabled some significant performance optimizations
over the years, but it has also proved difficult to work with and
occasionally surprising. A recent linux-kernel discussion showed how
splice() can cause trouble, to the point that some developers now
wonder if adding it was a good idea.

Security updates for Friday

Post Syndicated from original https://lwn.net/Articles/923644/

Security updates have been issued by Debian (webkit2gtk and wpewebkit), Fedora (firefox, phpMyAdmin, tpm2-tools, and tpm2-tss), Slackware (mozilla), SUSE (mozilla-nss, rubygem-actionpack-4_2, rubygem-actionpack-5_1, and tar), and Ubuntu (linux-azure and linux-hwe-5.19).

Defending against AI Lobbyists

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/02/defending-against-ai-lobbyists.html

When is it time to start worrying about artificial intelligence interfering in our democracy? Maybe when an AI writes a letter to The New York Times opposing the regulation of its own technology.

That happened last month. And because the letter was responding to an essay we wrote, we’re starting to get worried. And while the technology can be regulated, the real solution lies in recognizing that the problem is human actors—and those we can do something about.

Our essay argued that the much heralded launch of the AI chatbot ChatGPT, a system that can generate text realistic enough to appear to be written by a human, poses significant threats to democratic processes. The ability to produce high quality political messaging quickly and at scale, if combined with AI-assisted capabilities to strategically target those messages to policymakers and the public, could become a powerful accelerant of an already sprawling and poorly constrained force in modern democratic life: lobbying.

We speculated that AI-assisted lobbyists could use generative models to write op-eds and regulatory comments supporting a position, identify members of Congress who wield the most influence over pending legislation, use network pattern identification to discover undisclosed or illegal political coordination, or use supervised machine learning to calibrate the optimal contribution needed to sway the vote of a legislative committee member.

These are all examples of what we call AI hacking. Hacks are strategies that follow the rules of a system, but subvert its intent. Currently a human creative process, future AIs could discover, develop, and execute these same strategies.

While some of these activities are the longtime domain of human lobbyists, AI tools applied against the same task would have unfair advantages. They can scale their activity effortlessly across every state in the country—human lobbyists tend to focus on a single state—they may uncover patterns and approaches unintuitive and unrecognizable by human experts, and do so nearly instantaneously with little chance for human decision makers to keep up.

These factors could make AI hacking of the democratic process fundamentally ungovernable. Any policy response to limit the impact of AI hacking on political systems would be critically vulnerable to subversion or control by an AI hacker. If AI hackers achieve unchecked influence over legislative processes, they could dictate the rules of our society: including the rules that govern AI.

We admit that this seemed far fetched when we first wrote about it in 2021. But now that the emanations and policy prescriptions of ChatGPT have been given an audience in the New York Times and innumerable other outlets in recent weeks, it’s getting harder to dismiss.

At least one group of researchers is already testing AI techniques to automatically find and advocate for bills that benefit a particular interest. And one Massachusetts representative used ChatGPT to draft legislation regulating AI.

The AI technology of two years ago seems quaint by the standards of ChatGPT. What will the technology of 2025 seem like if we could glimpse it today? To us there is no question that now is the time to act.

First, let’s dispense with the concepts that won’t work. We cannot solely rely on explicit regulation of AI technology development, distribution, or use. Regulation is essential, but it would be vastly insufficient. The rate of AI technology development, and the speed at which AI hackers might discover damaging strategies, already outpaces policy development, enactment, and enforcement.

Moreover, we cannot rely on detection of AI actors. The latest research suggests that AI models trying to classify text samples as human- or AI-generated have limited precision, and are ill equipped to handle real world scenarios. These reactive, defensive techniques will fail because the rate of advancement of the “offensive” generative AI is so astounding.

Additionally, we risk a dragnet that will exclude masses of human constituents that will use AI to help them express their thoughts, or machine translation tools to help them communicate. If a written opinion or strategy conforms to the intent of a real person, it should not matter if they enlisted the help of an AI (or a human assistant) to write it.

Most importantly, we should avoid the classic trap of societies wrenched by the rapid pace of change: privileging the status quo. Slowing down may seem like the natural response to a threat whose primary attribute is speed. Ideas like increasing requirements for human identity verification, aggressive detection regimes for AI-generated messages, and elongation of the legislative or regulatory process would all play into this fallacy. While each of these solutions may have some value independently, they do nothing to make the already powerful actors less powerful.

Finally, it won’t work to try to starve the beast. Large language models like ChatGPT have a voracious appetite for data. They are trained on past examples of the kinds of content that they will be asked to generate in the future. Similarly, an AI system built to hack political systems will rely on data that documents the workings of those systems, such as messages between constituents and legislators, floor speeches, chamber and committee voting results, contribution records, lobbying relationship disclosures, and drafts of and amendments to legislative text. The steady advancement towards the digitization and publication of this information that many jurisdictions have made is positive. The threat of AI hacking should not dampen or slow progress on transparency in public policymaking.

Okay, so what will help?

First, recognize that the true threats here are malicious human actors. Systems like ChatGPT and our still-hypothetical political-strategy AI are still far from artificial general intelligences. They do not think. They do not have free will. They are just tools directed by people, much like lobbyist for hire. And, like lobbyists, they will be available primarily to the richest individuals, groups, and their interests.

However, we can use the same tools that would be effective in controlling human political influence to curb AI hackers. These tools will be familiar to any follower of the last few decades of U.S. political history.

Campaign finance reforms such as contribution limits, particularly when applied to political action committees of all types as well as to candidate operated campaigns, can reduce the dependence of politicians on contributions from private interests. The unfair advantage of a malicious actor using AI lobbying tools is at least somewhat mitigated if a political target’s entire career is not already focused on cultivating a concentrated set of major donors.

Transparency also helps. We can expand mandatory disclosure of contributions and lobbying relationships, with provisions to prevent the obfuscation of the funding source. Self-interested advocacy should be transparently reported whether or not it was AI-assisted. Meanwhile, we should increase penalties for organizations that benefit from AI-assisted impersonation of constituents in political processes, and set a greater expectation of responsibility to avoid “unknowing” use of these tools on their behalf.

Our most important recommendation is less legal and more cultural. Rather than trying to make it harder for AI to participate in the political process, make it easier for humans to do so.

The best way to fight an AI that can lobby for moneyed interests is to help the little guy lobby for theirs. Promote inclusion and engagement in the political process so that organic constituent communications grow alongside the potential growth of AI-directed communications. Encourage direct contact that generates more-than-digital relationships between constituents and their representatives, which will be an enduring way to privilege human stakeholders. Provide paid leave to allow people to vote as well as to testify before their legislature and participate in local town meetings and other civic functions. Provide childcare and accessible facilities at civic functions so that more community members can participate.

The threat of AI hacking our democracy is legitimate and concerning, but its solutions are consistent with our democratic values. Many of the ideas above are good governance reforms already being pushed and fought over at the federal and state level.

We don’t need to reinvent our democracy to save it from AI. We just need to continue the work of building a just and equitable political system. Hopefully ChatGPT will give us all some impetus to do that work faster.

This essay was written with Nathan Sanders, and appeared on the Belfer Center blog.

„Евроинс“ в Румъния е с 16 глоби за общо €2,3 млн. от 2020 г. насам

Post Syndicated from Екип на Биволъ original https://bivol.bg/%D0%B5%D0%B2%D1%80%D0%BE%D0%B8%D0%BD%D1%81-%D0%B2-%D1%80%D1%83%D0%BC%D1%8A%D0%BD%D0%B8%D1%8F-%D0%B5-%D1%81-16-%D0%B3%D0%BB%D0%BE%D0%B1%D0%B8-%D0%B7%D0%B0-%D0%BE%D0%B1%D1%89%D0%BE-e2.html

петък 17 февруари 2023


От 1 година срещу Euroins România Asigurare-Reasigurare S.A. (Euroins România на българската „Евроинс иншурънс груп“, част от „Еврохолд България“ АД) се води разследване от Органа за финансов надзор на Румъния…

Парламентарни избори 2023 – предварителна информация за чужбина

Post Syndicated from original https://yurukov.net/blog/2023/izbori2023-ranna-informaciq/

Тази информация беше изпратена на 12-ти февруари на над 3000 абонирали се в Glasuvam.org.


На 2-ри април 2023 ще се проведат избори за Народно събрание. Очакваме в рамките на следващите дни да бъде пуснат формуляра за гласуване. Когато това стане, ще изпратя нов мейл с линк към него към всички абонирани за информация на Glasuvam.org. Както и преди ще има картата за следене къде се събират заявления за гласуване и колко не стигат. Това, което знаем от сега е, че подаването на заявленията ще приключи на 7-ми март вечерта, след което ще бъдат определени местата и броя на секциите.

С последните промени на изборния кодекс се въведоха няколко усложнения, които особено засягат българите в чужбина. Най-основното от тях е ефективното връщане на хартиената бюлетина. Така разписан процесът ще удължи времето за гласуване, както и броенето на бюлетините.

Една отдавна чакана промяна беше МИР Чужбина. То отново няма да влезе в сила, тъй като мнозинството от депутатите отказаха да разпишат как точно да бъде приложен. Въпреки опитите в същия пакет от промени за драстично увеличение на нужните заявления за отваряне на секция зад граница, те остават непроменени.

Остава правилото, че ще бъдат автоматично одобрени секции там, където на някой вот в последните 5 години е имало поне 100 гласували. Отделно се откриват в дипломатическите представителства и за където са събрани поне 40 заявления. Отново е добра идея да се организирате на местно ниво, за да се посочва едно и също име на мястото в падащия списък, защото ЦИК не ги групира изрично дори да изглеждат еднакви.

Това не означава, че на тези места непременно ще бъдат открити секции. За да се случи това, трябва да има помещение, секционна комисия и доброволци. Ако бихте искали да помагате с организацията, свържете се с местната българска организация или дипломатическо представителство. Може да станете членове на комисия или наблюдатели също, ако сте част от партия или регистрирана за изборите организация. В такъв случай се свържете с тях.

Подаването на заявления за гласуване не е задължително, но ускорява много процеса на гласуване. Помага също да не гласуват от Ваше име по постоянен адрес, тъй като Ви отписват от списъка там. Не на последно място допринася да се отворят секции и дава някаква индикация за очакваната активност по време на избори.

Една друга промяна е, че тази година смених начина, по който се изпращат мейлите с инфорамцията. Така трябва да е много по-прегледно и надеждно. Ако искате да се абонирате, може да го направите на страницата на Glasuvam.org посочвайки кой е най-близкият до вас град, в който бихте искали да има секция.

The post Парламентарни избори 2023 – предварителна информация за чужбина first appeared on Блогът на Юруков.

Научни новини: нов механизъм за борба с COVID-19 и пръстени вместо луни

Post Syndicated from Михаил Ангелов original https://www.toest.bg/nauchni-novini/

Медицина

COVID-19

Научни новини: нов механизъм за борба с COVID-19 и пръстени вместо луни

За да заразят клетките, вирусните частици обикновено се закачат за рецептори, намиращи се по тяхната повърхност, и така преминават през клетъчната мембрана. Един от добре проучените рецептори е ACE2, към който са специфични спайкпротеините на някои коронавируси, включително причинителите на SARS и COVID-19. Той се среща в редица тъкани, наред с горните части на дихателната система, които са един от основните пътища за навлизането му в тялото.

Учени от Австралия са открили нов рецептор – LRRC15, който също може да свързва SARS-CoV-19, но за разлика от ACE2, той не съдейства на вируса да навлезе в клетките, а помага за предпазване от заболяването. Екипът го описва като молекулярно велкро, което се прилепя към вирионите и ги отдалечава от клетките, пречейки им да ги заразят.

Подобно на ACE2, този протеин е разпространен в различни тъкани, но количеството му в белите дробове е сравнително ниско при здрави хора. При болни от COVID-19 нивото му се повишава, откъдето идва и хипотезата, че е налице непознат до момента механизъм за борба с инфекцията.

Това се подкрепя от изследване на пациенти с бъбречна недостатъчност, при които нивата на LRRC15 са пряко свързани с тежестта на протичане на заболяването им от COVID-19. С намаляване на концентрацията на протеина симптомите стават по-сериозни и прогнозата се влошава.

Наред със свързването на вирусните частици, отделянето на този протеин от клетките, причиняващи лезии по белите дробове (фибробласти), намалява образуването на колаген при срещата им с вируса и така предпазва органа от дълготрайни увреждания.

Авторите смятат, че това откритие ще помогне за разработването на нови медикаменти за облекчаване на симптомите от инфекции, причинени от сходни вируси, както и за предпазване от белодробна фиброза. Публикацията показва колко малко знаем за имунната система, и дава поле за бъдещи изследвания в тази област.

Вече е известно, че по време на бременност жените са изложени на повишен риск от COVID-19. Заболяването протича по-остро и при новородените, поради което лекарите препоръчват на бъдещите майки да минат пълен ваксинационен курс. Това се подкрепя от изследване на почти 9000 бебета под 6 месеца.

При двукратна ваксинация вероятността децата да бъдат защитени от вируса е 95% за Делта и 45% за Омикрон вариантите. Вероятността за избягване на хоспитализация е съответно 97% и 53%. Проучването показва, че е най-добре втората ваксинация да се направи по време на третия триместър. Поставянето на трета доза подобрява резултатите за Омикрон, повишавайки защитата от инфекция на 73%.

Тези данни потвърждават редица проучвания, показващи ползата от ваксините, и дават поглед върху по-малко обследвана част от популацията, а именно децата под 6-месечна възраст.

Птичи грип

Глобалната ситуация с разпространението на H5N1 продължава да е динамична и притеснителна. Вирусът е Инфлуенца тип А и е описан за пръв път през 1996 г. в Китай. Характерно за него е, че е силно вирулентен и има свойството да мутира бързо, както повечето РНК вируси. Наред с това, тъй като геномът му е сегментиран, той може да обменя части с други грипни вируси, което му позволява по-лесно да прескача между различни видове.

Съобщенията за загинали животни не са нови – в началото на миналата година в Гърция бяха открити труповете на над 500 къдроглави пеликана, случаи имаше и в Англия, Израел, Канада. Освен за дивите животни, вирусът е проблемен и за птиците във ферми поради високата гъстота на отглеждане и близкия контакт, на който са изложени. Според здравните служби на САЩ в последната година от заболяването са засегнати над 50 млн. птици.

Особено тревожни са новините за прескачането на вируса към бозайници. В Англия, Шотландия и Уелс са установени случаи при лисици и видри, а в началото на тази година в Перу са намерени почти 600 морски лъва, които най-вероятно са загинали от H5N1. Много притеснително е откриването на вируса и във ферма за норки в Испания. Горният респираторен тракт на норките е много сходен с човешкия, което създава рискове за рекомбинация и междувидово прескачане към работниците в тези ферми. Вероятно животните са се заразили от храната си, която е включвала птичи субпродукти.

За момента специалистите от СЗО смятат, че вероятността за инфекции при хора е малка. Оптимална среда за развитието на вируса са птиците, което налага срещата му с човешки вирус в тях. Едва след рекомбинация между двата генома той придобива възможността да прескочи в хора. Но дори и това не гарантира способността за заразяване от човек на човек – нужни са допълнителни мутации. Въпреки това, поради големия брой случаи, всички малки шансове се натрупват и опасността не трябва да бъде пренебрегвана, както се вижда от случая в Испания, където е установен пренос от една норка към друга

Все още не е напълно ясно и каква е смъртността от вируса при хора. От случаите, известни до момента, тя е много висока – 56%, но това може да се дължи и на факта, че хората с по-леки симптоми не са потърсили медицинска помощ и съответно не са диагностицирани и включени в статистиката.

Тъй като учените следят вируса от появата му и са предвидили пандемичния му потенциал, за него вече има няколко ваксини. Притеснителното е, че четири от петте ваксини, одобрени в ЕС, се произвеждат в кокоши яйца. Това създава два големи проблема. Първо, не е ясно дали компанията, произвеждаща ваксината си в тъканни култури, ще успее да предостави достатъчно бързо голям брой дози при необходимост. Второ, масовото производство зависи от най-вероятната жертва на вируса, при която смъртността е над 90%. Очаква се компаниите, произвеждащи mRNA ваксини за SARS-CoV-19, да адаптират технологията и за Инфлуенца, но това ще отнеме време както по технологични, така и по регулаторни причини.

Ако искате да прочетете повече по темата за междувидовото прескачане, горещо препоръчвам книгата Spillover: Animal Infections and the Next Human Pandemic на Дейвид Куамен. Въпреки че е издадена преди COVID-19, случаите в нея са интересни и може да се научи много за науката и историята зад редица епидемии.

Космос

Ракети и двигатели

След дълга подготовка SpaceX успешно изпита двигателите на бустера Super Heavy. Той е в основата на напълно преизползваемата ракета Starship, която компанията планира да включи в програмата „Артемис“, а в бъдеще – и в колонизацията на Марс.

Продължителността на теста е била с пълната предвидена дължина, като според информация от Илън Мъск един от двигателите е изключен от инженерите, а друг е отказал по време на работа. Той обаче смята, че останалите работещи двигатели са достатъчни за достигане на орбита. Това е голяма стъпка за проекта, тъй като дава зелена светлина за изпитанията на ракетата. Следващото най-вероятно ще е орбитален тест.

Интересно за Super Heavy е, че използва 33 двигателя за задвижването си. В повечето случаи проектантите се спират на по-малък брой по-големи двигатели, тъй като това намалява вероятността за проблем в някой от тях и значително опростява ракетата.

Изключение е замислената като отговор на лунната програма „Аполо“ съветска ракета Н-1, чиято първа степен има 30 двигателя, работещи с керосин и течен кислород. Програмата е обречена заради политически интриги и неразбирателство между главните проектанти и след четири неуспешни изстрелвания, водещи до катастрофални експлозии, е прекратена заедно с амбициите на СССР да спечелят лунната надпревара.

Главоболия имат и наследниците им от „Роскосмос“ – един от товарните апарати „Прогрес МС-21“, в момента скачен към Международната космическа станция, е загубил налягане в охладителната си система. В изявленията на руската агенция и НАСА се казва, че няма опасност за седемте космонавти в станцията, като температурата и налягането в обитаемия отсек са нормални. Все още не е ясно на какво се дължи тази авария, но двете агенции разследват случая. Товарният апарат вече е напълнен с отпадъци и по график ще напусне МКС на 18 февруари и ще изгори в атмосферата над Тихия океан.

Това е вторият сходен случай с руски апарат. В края на миналата година „Союз МС-22“, с който на станцията пристигнаха двама руски и един американски космонавт, също загуби охлаждането си, като официално обявената причина беше удар от микрометеорит. Това наложи удължаването на престоя на екипажа, който ще изчака изстрелването на „Союз МС-23“ без пътници, а повреденият „Союз МС-22“ ще бъде разкачен в безпилотен режим и оставен да изгори в атмосферата.

Въпреки че все още няма информация за инцидента с „Прогрес МС-21“, вероятността за втори аналогичен удар от микрометеорит в рамките на няколко месеца е малка. Това повдига редица въпроси относно причината за повредата в „Союз МС-22“ и състоянието на руската космическа програма.

Пръстен вместо луна

Пръстените около небесните тела са една от впечатляващите гледки, които Космосът ни предоставя. До момента се смяташе, че процесът на образуването им е добре проучен, но ново откритие в периферията на Слънчевата система може да промени това.

Планетата джудже Куауар е с диаметър около 1000 км и се намира в пояса на Кайпер – зона след орбитата на Нептун със сравнително ниска плътност и дом на множество подобни малки обекти, най-големият от които е Плутон. След откриването ѝ през 2002 г. астрономите установяват, че има естествен спътник, наречен Уейуот, а вече е известно, че има и система от пръстени. Те са прекалено малки и бледи, което прави директното им наблюдение невъзможно.

За откритието учените са използвали най-големия оптичен телескоп Gran Telescopio Canarias, намиращ се на остров Палма. С помощта на математически модел те са предвидили преминаването на планетата пред далечна звезда, т.нар. окултация. По време на наблюдението с телескопа, яркостта на звездата е намаляла преди и след преминаването на планетата на равни интервали. Наблюдението е направено неколкократно с няколко звезди. Най-вероятното обяснение за такива симетрични окултации е наличието на пръстен около планетата.

Учудващо е, че според получените данни пръстенът е разположен на разстояние 7,4 радиуса от планетата, което е два пъти над границата на Рош. Това е пределът, след който приливните сили от гравитацията на по-голямото тяло може да разкъсат малки тела в орбитата му. Според научните разбирания и симулации в момента, пръстените извън зоната на този ефект за кратко време започват да агрегират в луни.

Възможни са различни хипотези за обяснението на това наблюдение, но учените проучват комбинация от няколко фактора. Планетата може да има неравномерна форма и като следствие от това нейното гравитационно поле да се променя при въртенето ѝ – ефект, който би попречил на образуването на обекти на по-далечно разстояние. Пръстенът пък се намира в орбитален резонанс с отношение 1:3 с въртенето на планетата, което означава, че частиците в пръстена правят една орбита около планетата, докато в същото време тя се завърта три пъти около оста си, оказвайки им периодично гравитационно влияние.

Според авторите това може да помага за задържането на пръстена и да пречи на образуването на втора луна. Сходен орбитален резонанс имат и пръстените на планетите джуджета Харикло и Хаумея, но при тях те се намират в границата на Рош.

Това откритие е интересно, защото показва, че дори за добре приети идеи с история от над 150 години, може да бъдат открити изключения, вълнуващи научните среди.

Заглавно изображение: Микроскопска снимка на епителни клетки, 100х увеличение. Източник: Berkshire Community College Bioscience Image Library/Flickr

Веднъж-дваж месечно Михаил Ангелов – биолог, агроном и любим нърд от нашия екип, ни представя най-интересните скорошни новини от различни сфери на науката и обяснява защо тези постижения са толкова значими за света и човечеството. Или най-малкото – любопитни и забавни.

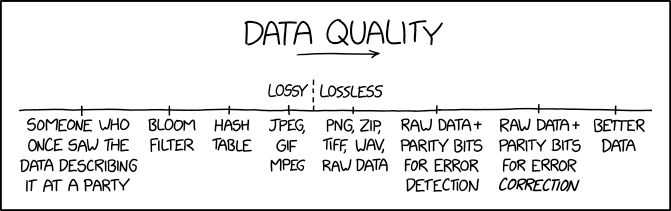
Data Quality

Post Syndicated from original https://xkcd.com/2739/

Supermicro A3SPI-4C-LN6PF Review Intel Atom C5315 Parker Ridge is Here

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/supermicro-a3spi-4c-ln6pf-review-intel-atom-c5315-parker-ridge-is-here/

In our Supermicro A3SPI-4C-LN6PF review, we test the new Intel Atom C5315 “Parker Ridge” SoC and find a feature we were not expecting onboard

The post Supermicro A3SPI-4C-LN6PF Review Intel Atom C5315 Parker Ridge is Here appeared first on ServeTheHome.

So long, and thanks for all the deployments: deprecating Wrangler v1

Post Syndicated from Cass Fridkin original https://blog.cloudflare.com/deprecating-wrangler-v1/

So long, and thanks for all the deployments:  deprecating Wrangler v1

So long, and thanks for all the deployments:  deprecating Wrangler v1

Cloudflare Workers allow developers to deploy code instantly across the globe. Wrangler is the CLI tool we build (and use!) to create, modify, and upload Workers. We recently announced a new version of Wrangler with a bunch of new features – including offline development, zero-config startup, and developer tools support. Since then, we’ve been working hard to make the developer experience with version 2 as smooth and enjoyable as possible. We’re confident in what we’ve built and are now planning to officially deprecate version 1.

What’s happening?

Version 1 of Wrangler (@cloudflare/wrangler on npm) is now deprecated, which means no new features or bug fixes will be published unless they’re critical. Beginning August 2023, no further updates will be provided and the Wrangler v1 GitHub repo will be archived. We strongly recommend you upgrade to version 2 (wrangler on npm) to receive continued support. We have a migration guide to make this process easy!

Why?

Our goal is to make development on the Cloudflare platform as smooth and enjoyable as possible. Whether that means simplifying common workflows, incorporating powerful tools into the Wrangler codebase, or opening up Wrangler for use as a library, we want Wrangler to be a one-stop shop for developing on Cloudflare.

With that in mind, last year we set out to align our product with our goals. Wrangler was the primary way developers interacted with our platform, but the codebase was difficult to maintain and had spiraled in complexity. Weighing our options, we found that the best way forward was a total rewrite of Wrangler, culminating in the 2.0 release.

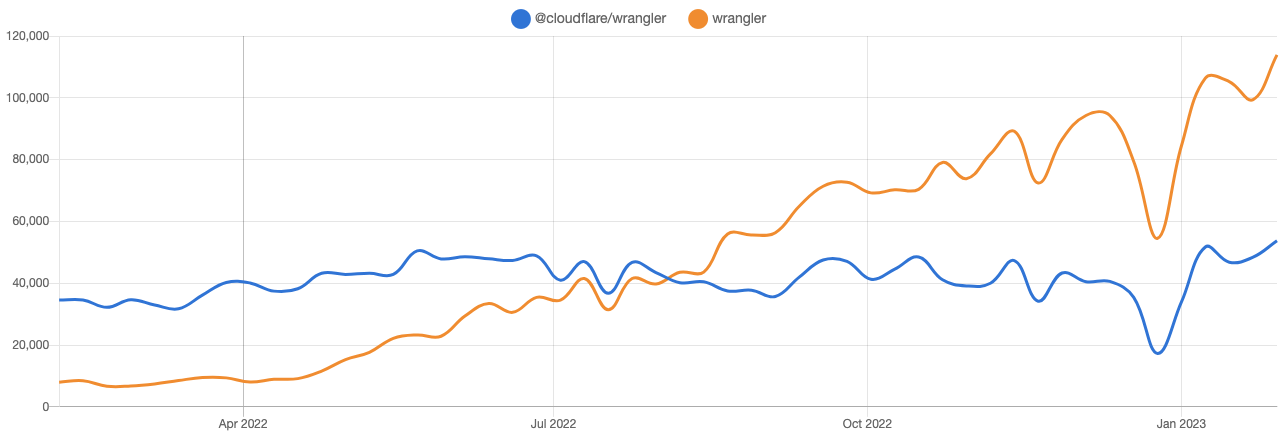
Typically, semver-major releases (such as 1.x to 2.0) introduce breaking changes into a codebase – making it non-trivial to update to the latest version of software. While some breakage was inevitable with the release of a new major version of Wrangler, we aimed to ensure smooth upgrades. We provided detailed deprecation messages and documented breaking changes wherever they occurred. We carefully monitored issue reports, and responded with updates to fix problems. We monitored download statistics of both versions of wrangler, and celebrated internally when downloads for version 2 of Wrangler surpassed downloads for version 1 on npm.

So long, and thanks for all the deployments:  deprecating Wrangler v1
Download statistics for @cloudflare/wrangler (version 1, in blue) and wrangler (version 2, in orange). Source: https://npmtrends.com/@cloudflare/wrangler-vs-wrangler

What do I need to do?

For most of our users, deprecation of version 1 will be invisible – they’re already on version 2! If you’re still on version 1, please upgrade – we have a migration guide that details everything you need to do to update to the latest and greatest version. If you encounter any bugs, unexpected behavior, or anything blocking you from upgrading, file an issue! If you’re not using Wrangler, give it a shot! We’re really proud of what we’ve built, and we want your feedback on how we can continue to make it even better.

Fastly vs. AWS CloudFront: How Do the CDNs Stack Up?

Post Syndicated from Molly Clancy original https://www.backblaze.com/blog/fastly-vs-aws-cloudfront-how-do-the-cdns-stack-up/

As a leading specialized cloud platform for application storage, we work with a variety of content delivery network (CDN) providers. From this perch, we get to see the specifics on how each operates. Today, we’re sharing those learnings with you by comparing Fastly and AWS CloudFront to help you understand your options when it comes to choosing a CDN. 

A Guide to CDNs

This article is the first in a series on all things CDN. We’ll cover how to decide which CDN is best for you, how to decipher pricing, and how to use a video CDN with cloud storage.

If there’s anything you’d like to hear more about when it comes to CDNs, let us know in the comments.

What Is a CDN?

If you run a website or a digital app, you need to ensure that you are delivering your content to your audience as quickly and efficiently as possible to beat out the competition. One way to do this is by using a CDN. A CDN caches all your digital assets like videos, images, scripts, style sheets, apps, etc. Then, whenever a user accesses your content, the CDN connects them with the closest server so that your items load quickly and without any issues. Many CDNs have servers around the globe to offer low-latency data access and drastically improve the responsiveness of your app through caching.

Before you choose a CDN, you need to consider your options. There are dozens of CDNs to choose from, and they all have benefits and drawbacks. Let’s compare Fastly with AWS CloudFront to see which works best for you.

CDN Use Cases

Before we compare these two CDNs, it’s important to understand how they might fit into your overall tech stack. Here are some everyday use cases for a CDN:

  • Websites: If you have a video- or image-heavy website, you will want to use a CDN to deliver all your content without any delays for your visitors.
  • Web Applications: A CDN can help optimize your dynamic content and allow your web apps to run flawlessly, regardless of where your users access them.
  • Streaming Video: Customers expect more from companies these days and will not put up with buffering or intermittent video streaming issues. If you host a video streaming service like Hulu, Netflix, Kanopy, or Amazon, a CDN can solve these problems. You can host high-resolution (8K) video on your CDN and then stream it to your users, offering them a smooth, gapless streaming experience.
  • Gaming: If you are a “Call of Duty” or “Halo” fan, you know that most video games use high-resolution images and video to provide the most immersive gaming experience possible. Video game providers use CDNs to ensure responsive gameplay without any blips. You can also use a CDN to streamline rolling out critical patches or updates to all your customers without any limits.
  • E-Commerce Applications: Online retailers typically use dozens of images to showcase their products. If you want to use high-quality images, your website could suffer slow page loads unless you use a CDN to deliver all your photos instantly without any wait.

Need for Speed (Test)

Website developers and owners use speed tests to gauge page load speeds and other aspects affecting the user experience. A CDN is one way to improve your website metrics. You can use various online speed tests that show details like load time, time to first byte (TTFB), and the number of requests (how many times the browser must make the request before the page loads).

A CDN can help improve performance quite a bit, but speed tests are dependent on many factors outside of a CDN. To find out exactly how well your site performs, there are dozens of reputable speed test tools online that you can use to evaluate your site, and then you can make improvements from there. Some of the most popular tools are:

Comparing Fastly vs. AWS CloudFront

Fastly, founded in 2011, has rapidly grown to be a competitive global edge cloud platform and CDN offering international customers a wide variety of products and services. The company’s flagship product is its CDN which offers nearly instant content delivery for companies like The New York Times, Reddit, and Pinterest.

AWS CloudFront is Amazon Web Service’s (AWS) CDN offering. It’s tightly integrated with other AWS products.

To best understand how the two CDNs compare, we’ll look at different aspects of each one so you can decide which option works best for you, including:

  • Network
  • Caching
  • DDoS Protection
  • Log streaming
  • Integrations
  • TLS Protocols
  • Pricing

Network

CDN networks are made up of distribution points, which are network connections (servers) that allow a CDN to deliver content instantly to users anywhere.

Fastly

Fastly’s network is built fundamentally differently than a legacy CDN. Rather than a wide-ranging network populated with many points of presence (PoPs), Fastly built a stronger network based on fewer, more powerful, and strategically placed PoPs. Fastly promises 233Tbps of connected global capacity with its system of PoPs (as of 9/30/2022).

AWS CloudFront

AWS CloudFront doesn’t share specific capacity figures in terms of terabits per second (Tbps). They keep that claim somewhat vague, advertising “hundreds of terabits of deployed capacity.” But they do advertise that they have roughly 450 distribution points in 90 cities in 48 countries.

Our Take

At first glance, it might seem like more PoPs means a faster, more robust network. Fastly uses a useful metaphor to explain why that’s not true. They compare legacy PoPs to convenience stores—they’re everywhere, but they’re small, meaning that the content your users are requesting may not be there when they need it. Fastly’s PoPs are more like supermarkets—you have a better chance of getting everything you need (your cached content) in one place. It only takes a few milliseconds to get to one of Fastly’s PoPs nowadays (as opposed to when legacy providers like AWS CloudFront built their networks), and there’s much more likelihood that the content you need is going to be housed in that PoP already, instead of needing to be called up from origin storage.

Caching

Caching reduces the number of direct requests to your origin server. A CDN acts as a middleman responding to requests for content on your behalf and directing users to edge caches nearest to the user. When a user calls up your website, the CDN serves up a cached version located on the server closest to them. This feature drastically improves the speed and performance of your website.

Fastly

Fastly uses a process of calculating the Time to Live (TTL) with its caching feature. TTL is the maximum time Fastly will use the content to answer requests before returning to your origin server. You can set various cache settings like purging objects, conditional caching, and assigning different TTLs for cached content through Fastly’s API.

Fastly shows its average cache hit ratio live on its website, which is over 91% at the time of publication. This is the ratio of how many content requests the CDN is able to fill from the cache versus the total number of requests.

Fastly also allows you to automatically compress some file types in gzip and then cache them. You can modify these settings from inside Fastly’s web interface. The service also includes support for Brotli data compression via general availability as of February 7, 2023.

AWS CloudFront

AWS CloudFront routes requests for your content to servers holding a cached version, lessening the burden on your origin container. When users visit your site, the CDN directs them to the closest edge cache for instantaneous page loads. You can change your cache settings in AWS CloudFront’s backend. AWS CloudFront supports compressed files and allows you to store and access gzip and Brotli compressed objects.

Our Take

Fastly does not charge a fee no matter how many times content is purged from the cache, while AWS CloudFront does. And, Fastly can invalidate content in 150 milliseconds, while AWS CloudFront can be 60–120 times slower. Both of these aspects make Fastly better with dynamic content that changes quickly for customers, such as news outlets, social media sites, and e-commerce sites.

DDoS Protection

Distributed denial of service (DDoS) attacks are a serious concern for website and web app owners. A typical attack can interrupt website traffic or crash it completely, making it impossible for your customers to reach you.

Fastly

Fastly relies on its 233Tbps+ (as of 9/30/2022) of globally-distributed network capacity to absorb any DDoS attacks, so they don’t affect customers’ origin content. They also use sophisticated filtering technology to remove malicious requests at the edge before they get close to your origin.

AWS CloudFront

AWS CloudFront is backed by comprehensive security technology designed to prevent DDoS and other types of attacks. Amazon calls its DDoS protection service AWS Shield.

Our Take

Fastly’s next gen web application firewall (WAF) actively filters the correct traffic. More than 90% of their customers use the WAF in active full blocking mode whereas across the industry, only 57% of customers use their WAF in full blocking mode. This means the Fastly WAF works as it should out of the box. Other WAFs require more fine-tuning and advanced rule setting to be as efficient as Fastly’s. Fastly’s WAF can also be deployed anywhere—at the edge, on-premises, or both—whereas most AWS instances are cloud hosted.

Log Streaming

Log streaming enables you to collect logs from your CDN and forward them to specific destinations. They help customers stay on top of up-to-date information about what’s happening within the CDN, including detecting security anomalies.

Fastly

Fastly allows for near real-time visibility into delivery performance with real-time logs. Logs can be sent to 29 endpoints, including popular third-party services like Datadog, Sumo Logic, Splunk, and others where they can be monitored.

AWS CloudFront

AWS CloudFront real-time logs are integrated with Amazon Kinesis Data Streams to enable delivery using Amazon Kinesis Data Firehose. Kinesis Data Firehose can then deliver logs to Amazon S3, Amazon Redshift, Amazon Elasticsearch Service, as well as service providers like Datadog, New Relic, and Splunk. AWS charges for real-time logs in addition to charging for Kinesis Data Streams.

Our Take

More visibility into your data is always better, and Fastly’s free real-time log streaming is the clear winner here with more choice of endpoints, allowing customers to use the specialized third-party services they prefer. AWS encourages staying within the AWS ecosystem and penalizes customers for not using AWS services, namely their S3 object storage.

Integrations

Integrations allow you to extend a product or service’s functionality through add-ons. With your CDN, you might want to enhance it with a different interface or add on new features the original doesn’t include. One popular tool we’ll highlight here is Terraform, a tool that allows you to provision infrastructure as code (IaC).

Terraform

Both Fastly and AWS CloudFront support Terraform. Fastly has detailed instructions on its website about how to set this up and configure it to work seamlessly with the service.

Amazon’s AWS CloudFront allows you to integrate with Terraform by installing the program on your local machine and configuring it within AWS CloudFront’s configuration files.

The Drawbacks of a Closed Ecosystem

It’s important to note that AWS CloudFront, as an AWS product, works best with other AWS products, and doesn’t exactly play nice with competitor products. As an independent cloud services provider, Fastly is vendor agnostic and works with many other cloud providers, including AWS’s other products and Backblaze.

TLS (Transport Layer Security) Protocols

TLS or transport layer security (formerly known as secure sockets layer (SSL)) is an encryption device used to protect website data. Whenever you see the lock sign on your internet browser, you are using a website that is protected by an TLS (HTTPS).

Fastly assigns a shared domain name to your CDN content. You can use the associated TLS certificate for free or bring your own TLS certificate and install it. Fastly offers detailed instructions and help guides so you can securely configure your content.

Amazon’s AWS CloudFront also assigns a unique URL for your CDN content. You can use an Amazon-issued certificate, the default TLS certificate installed on the server or use your own TLS. If you use your own TLS, you must follow the explicit instructions for key length and install it correctly on the server.

Pricing

Fastly

Fastly offers a free trial which includes $50 of traffic with pay-as-you-go bandwidth pricing after that. Bandwidth pricing is based on geographic location and starts at, for example, $0.12 per GB for the first 10TB for North America. The next 10TB is $0.08 per GB, and they charge $0.0075 per 10,000 requests. Fastly also offers tiered capacity-based pricing for edge cloud services, starting with its Essential product for small businesses, which includes 3TB of global delivery per month. Their Professional tier includes 10TB of global delivery per month, and their Enterprise tier is unlimited. They also offer add-on products for security and distributed applications.

AWS CloudFront

AWS CloudFront offers a free plan including 1TB of data transfer out, 10,000,000 HTTP or HTTPS requests, and 2,000,000 functions invocations each month. However, customers needing more than the basic plan will have to consider the tiered pricing based on bandwidth usage. AWS CloudFront’s pricing starts at $0.085 per GB up to 10TB in North America. All told, there are seven pricing tiers from 10TB to >5PB.

Our Take

When it comes to content delivery, AWS CloudFront can’t compete on cost. Not only that, but Fastly’s pay-as-you-go pricing model with only two tiers is simpler than AWS CloudFront’s pricing with seven tiers. As with many AWS products, complexity demands configuration and management time. Customers tend to spend less time getting Fastly to work the way they want it to. With AWS CloudFront, customers also run the risk of getting locked in to the AWS ecosystem.

Our Final Take

Between the two CDNs, Fastly is the better choice for customers that rely on managing and serving dynamic content without paying high fees to create personalized experiences for their end users. Fastly wins over AWS CloudFront on a few key points:

  • More price competitive for content delivery
  • Simpler pricing tiers
  • Vendor agnostic
  • Better caching
  • Easier image optimization
  • Real-time log streaming
  • More expensive, but better performing out-of-the-box WAF

Using a CDN with Cloud Storage

A CDN can greatly speed up your website load times, but there will still be times when a request will call the origin store. Having reliable and affordable origin storage is key when the cache doesn’t have the content stored. When you pair a CDN with origin storage in the cloud, you get the benefit of both scalability and speed.

The post Fastly vs. AWS CloudFront: How Do the CDNs Stack Up? appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

Systemd 253 released

Post Syndicated from original https://lwn.net/Articles/923545/

Systemd 253 has been released. As always, the list of changes is
extensive. Support for version-1 control groups and separate /usr
systems is going away later this year. There is a new tool for working
with unified
kernel images
, a number of new unit-file options have been added, and
much more; click below for the full list.

Rapid7 CEO Corey E. Thomas Appointed To National Security Telecommunications Advisory Committee

Post Syndicated from Rapid7 original https://blog.rapid7.com/2023/02/16/rapid7-ceo-corey-e-thomas-appointed-to-national-security-telecommunications-advisory-committee/

Rapid7 CEO Corey E. Thomas Appointed To National Security Telecommunications Advisory Committee

President Biden has announced his intent to appoint a group of highly qualified and diverse industry leaders, including Rapid7 chairman & CEO Corey E. Thomas, to the President’s National Security Telecommunications Advisory Committee (NSTAC).

Rapid7 CEO Corey E. Thomas Appointed To National Security Telecommunications Advisory Committee

NSTAC’s mission is to to provide the best possible technical information and policy advice to assist the President and other stakeholders responsible for critical national security and emergency preparedness (NS/EP) services. The committee advises the White House on the reliability, security, and preparedness of vital communications and information infrastructure. It is focused on five key themes:

  • Strengthening national security
  • Enhancing cybersecurity
  • Maintaining the global communications infrastructure
  • Assuring communications for disaster response
  • Addressing critical infrastructure interdependencies and dependencies

Thomas joins a talented group of telecommunications and security executives from companies such as AT&T, Microsoft, Cisco, Lockheed Martin, T-Mobile, and Verizon. These executives bring diverse perspectives backed by years of unique industry experience.

“It is an extreme honor and privilege to be named to the President’s National Security Telecommunications Advisory Committee,” said Thomas. “I look forward to the remarkable opportunity to provide cybersecurity guidance to the President’s administration and to work alongside and learn from  this talented group of individuals, many of whom I’ve admired throughout my career.”

The collective thoughts of the interwebz