Post Syndicated from original https://lwn.net/Articles/910954/
The
6.0.1,
5.19.15, and
5.15.73
stable kernels have been released; each contains a relatively small set of
important fixes.
Post Syndicated from original https://lwn.net/Articles/910954/
The
6.0.1,
5.19.15, and
5.15.73
stable kernels have been released; each contains a relatively small set of
important fixes.
Post Syndicated from original https://lwn.net/Articles/910953/
Security updates have been issued by Debian (mediawiki and twig), Oracle (expat, gnutls and nettle, and kernel), Red Hat (expat, kernel, and kpatch-patch), and Ubuntu (advancecomp and dotnet6).
Post Syndicated from Omer Yoachimik original https://blog.cloudflare.com/cloudflare-ddos-threat-report-2022-q3/

Welcome to our DDoS Threat Report for the third quarter of 2022. This report includes insights and trends about the DDoS threat landscape – as observed across Cloudflare’s global network.
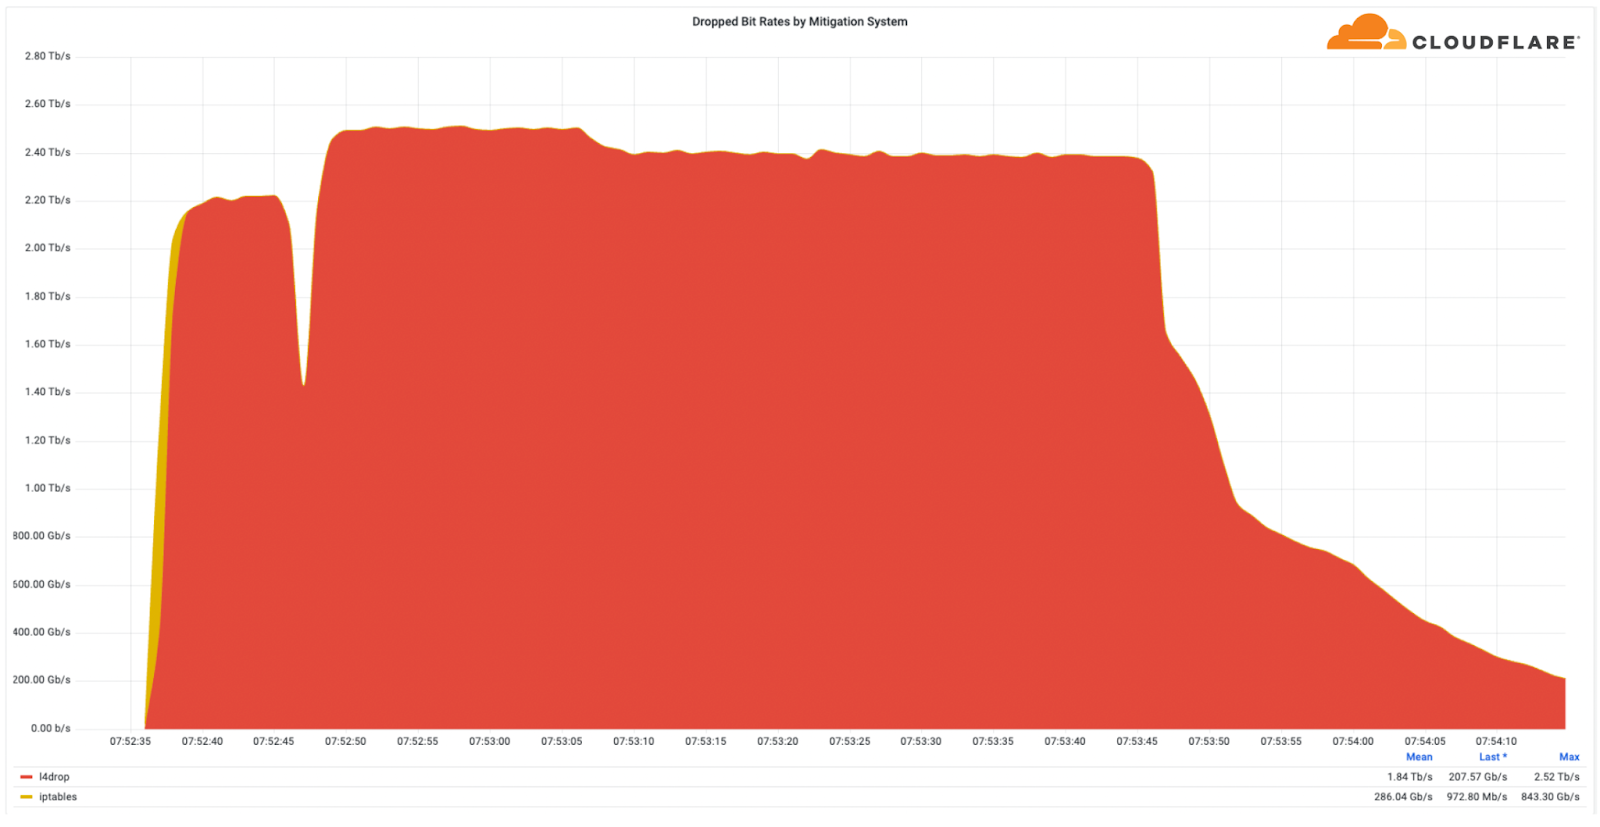
Multi-terabit strong DDoS attacks have become increasingly frequent. In Q3, Cloudflare automatically detected and mitigated multiple attacks that exceeded 1 Tbps. The largest attack was a 2.5 Tbps DDoS attack launched by a Mirai botnet variant, aimed at the Minecraft server, Wynncraft. This is the largest attack we’ve ever seen from the bitrate perspective.
It was a multi-vector attack consisting of UDP and TCP floods. However, Wynncraft, a massively multiplayer online role-playing game Minecraft server where hundreds and thousands of users can play on the same server, didn’t even notice the attack, since Cloudflare filtered it out for them.
Overall this quarter, we’ve seen:
This report is based on DDoS attacks that were automatically detected and mitigated by Cloudflare’s DDoS Protection systems. To learn more about how it works, check out this deep-dive blog post.
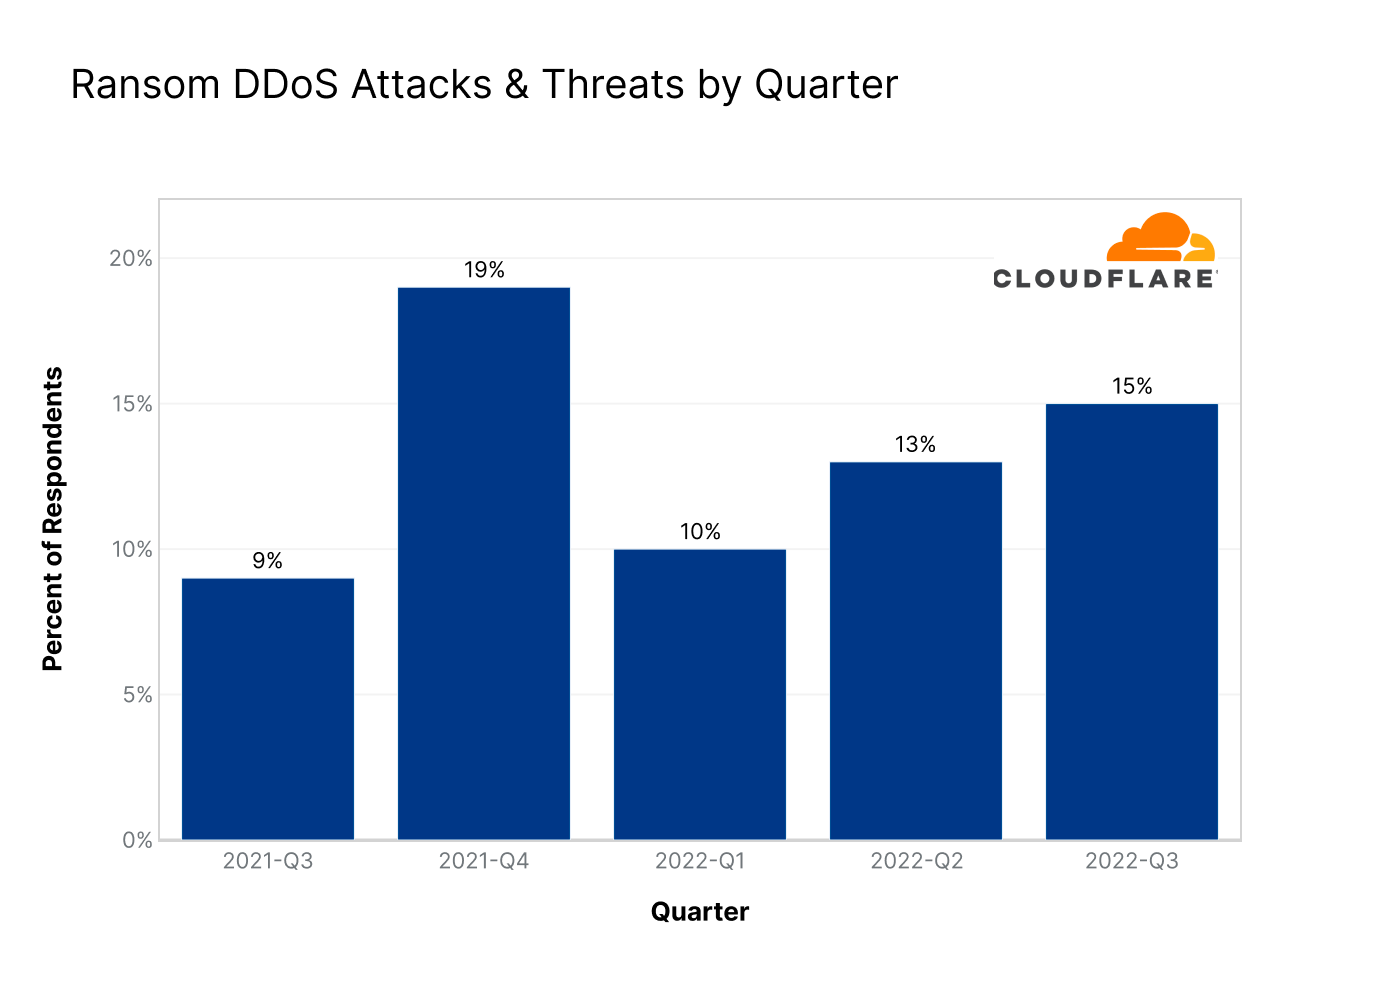
Ransom DDoS attacks are attacks where the attacker demands a ransom payment, usually in the form of Bitcoin, to stop/avoid the attack. In Q3, 15% of Cloudflare customers that responded to our survey reported being targeted by HTTP DDoS attacks accompanied by a threat or a ransom note. This represents a 15% increase QoQ and 67% increase YoY of reported ransom DDoS attacks.
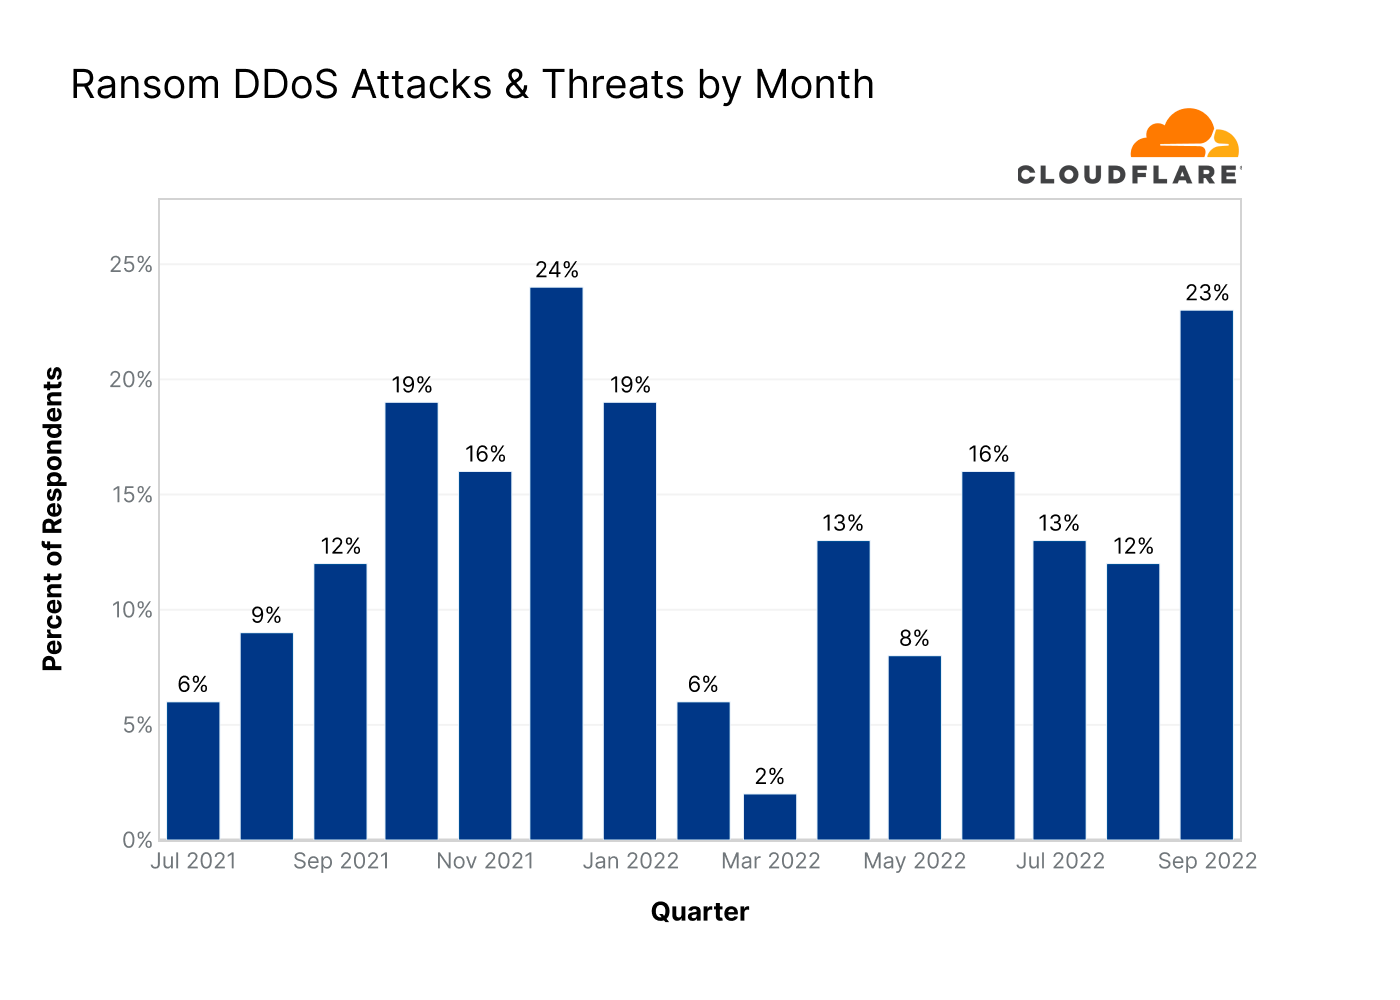
Diving into Q3, we can see that since June 2022, there was a steady decline in reports of ransom attacks. However, in September, the reports of ransom attacks spiked again. In the month of September, almost one out of every four respondents reported receiving a ransom DDoS attack or threat — the highest month in 2022 so far.
How we calculate Ransom DDoS attack trends
Our systems constantly analyze traffic and automatically apply mitigation when DDoS attacks are detected. Each DDoS’d customer is prompted with an automated survey to help us better understand the nature of the attack and the success of the mitigation. For over two years, Cloudflare has been surveying attacked customers. One of the questions in the survey asks the respondents if they received a threat or a ransom note demanding payment in exchange to stop the DDoS attack. Over the past year, on average, we collected 174 responses per quarter. The responses of this survey are used to calculate the percentage of Ransom DDoS attacks.
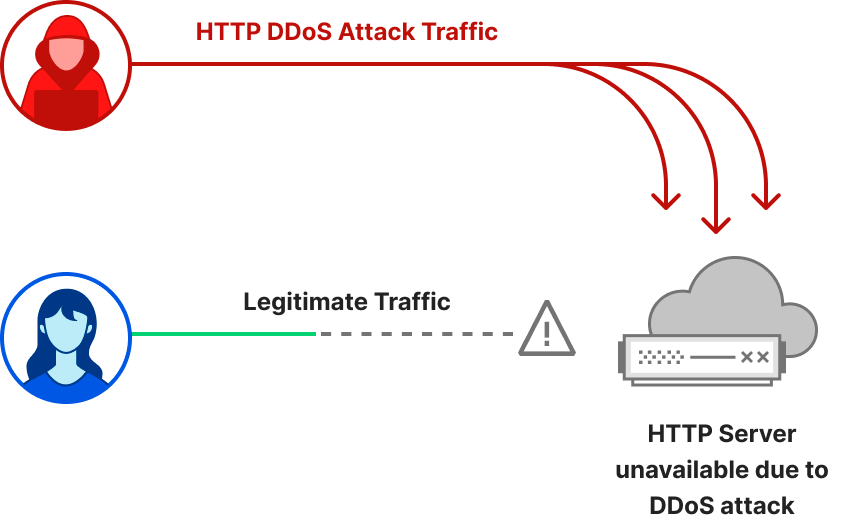
Application-layer DDoS attacks, specifically HTTP DDoS attacks, are attacks that usually aim to disrupt a web server by making it unable to process legitimate user requests. If a server is bombarded with more requests than it can process, the server will drop legitimate requests and – in some cases – crash, resulting in degraded performance or an outage for legitimate users.
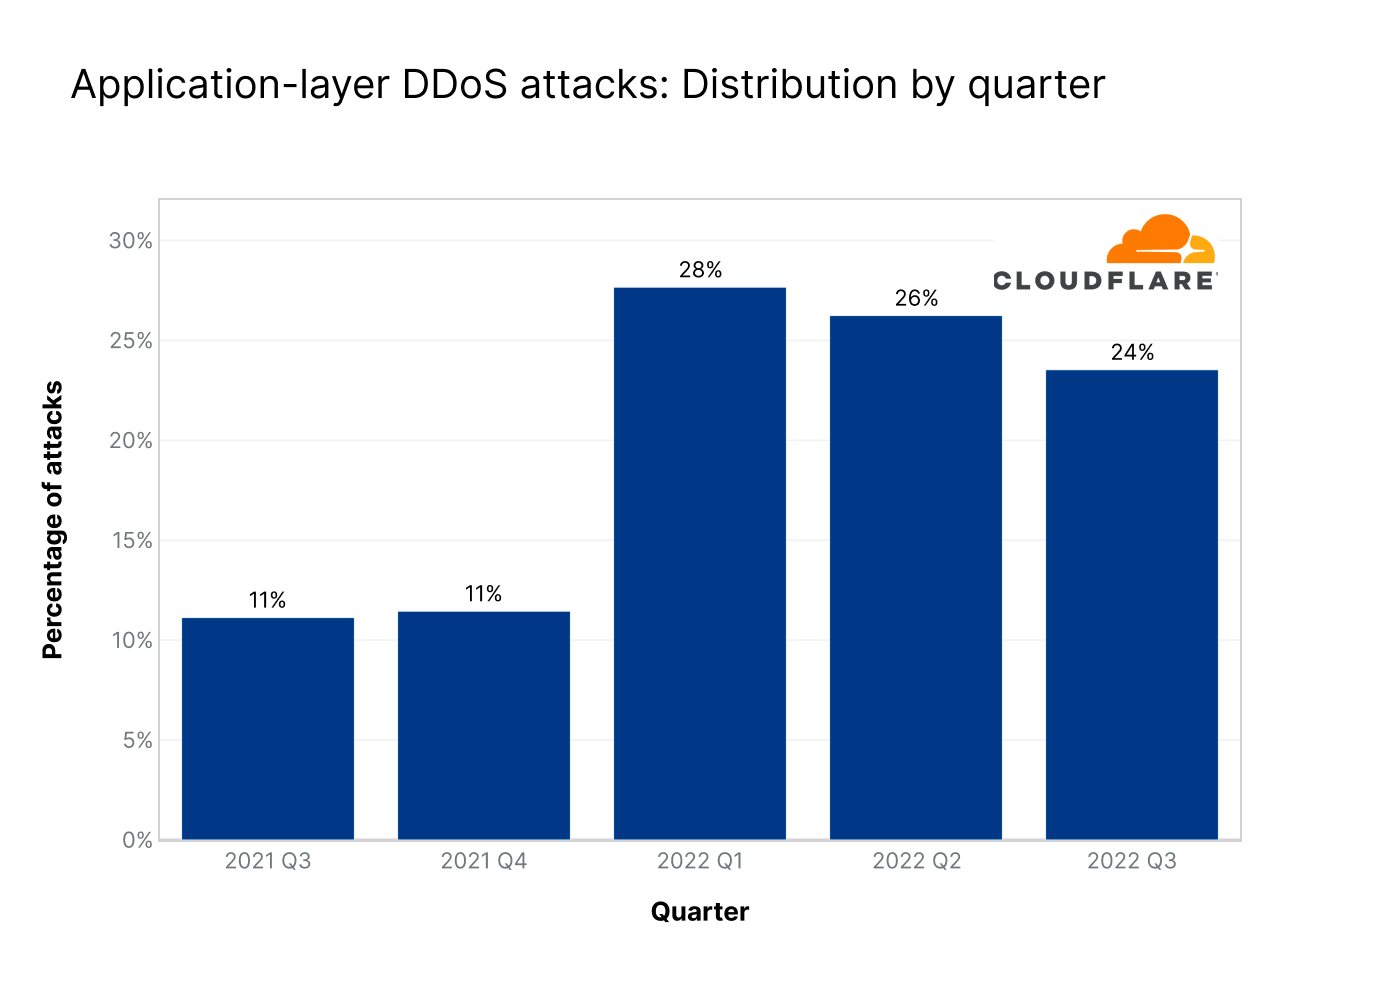
When we look at the graph below, we can see a clear trend of approximately 10% decrease in attacks each quarter since 2022 Q1. However, despite the downward trend, when comparing Q3 of 2022 to Q3 of 2021, we can see that HTTP DDoS attacks still increased by 111% YoY.
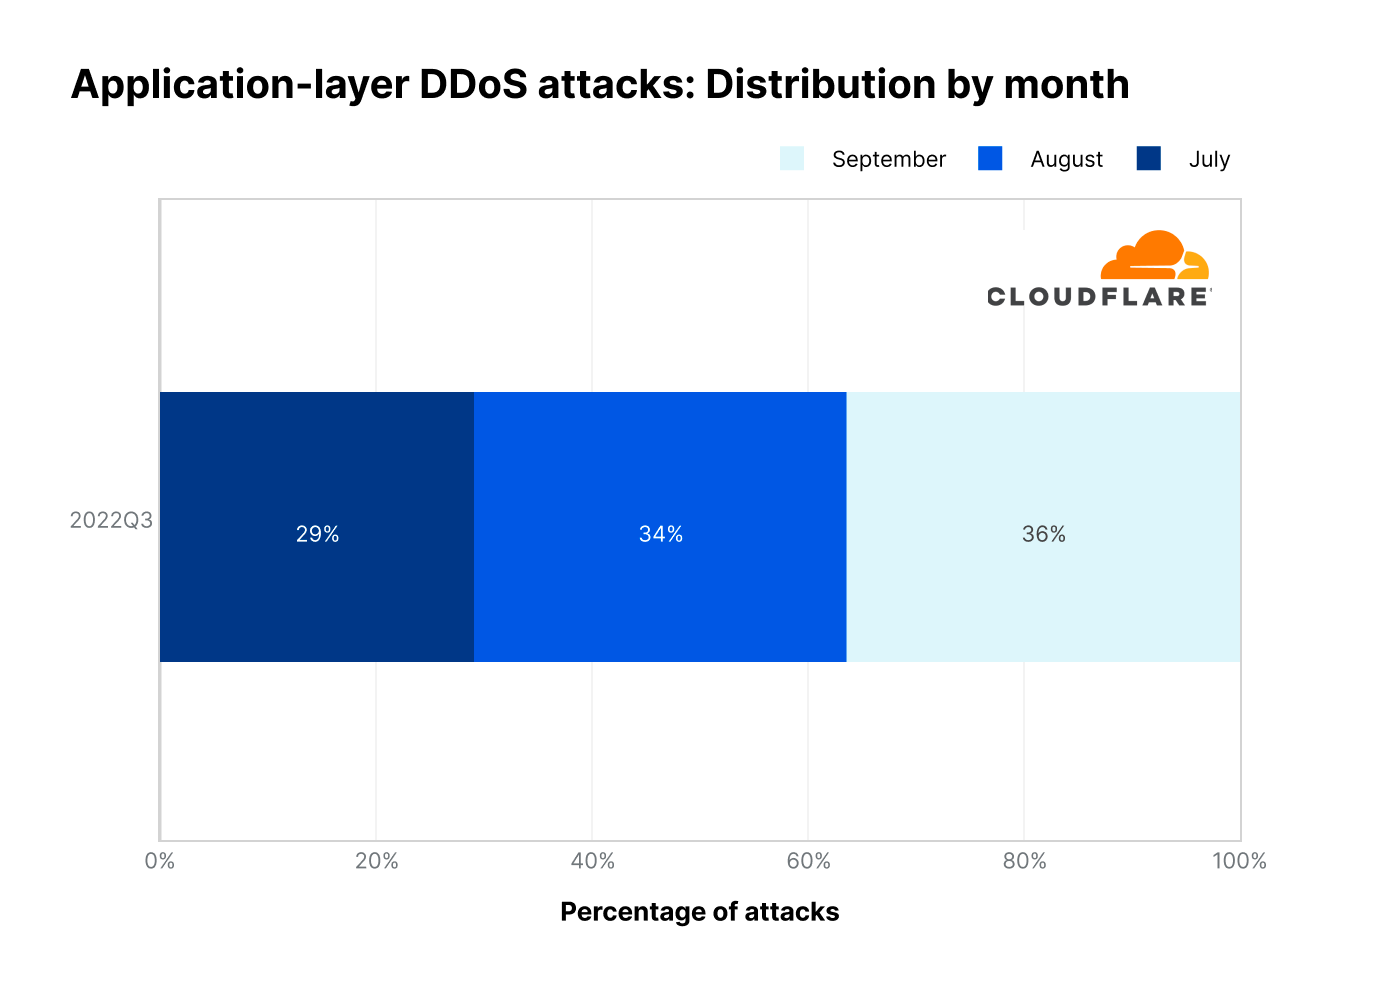
When we dive into the months of the quarter, attacks in September and August were fairly evenly distributed; 36% and 35% respectively. In July, the amount of attacks was the lowest for the quarter (29%).
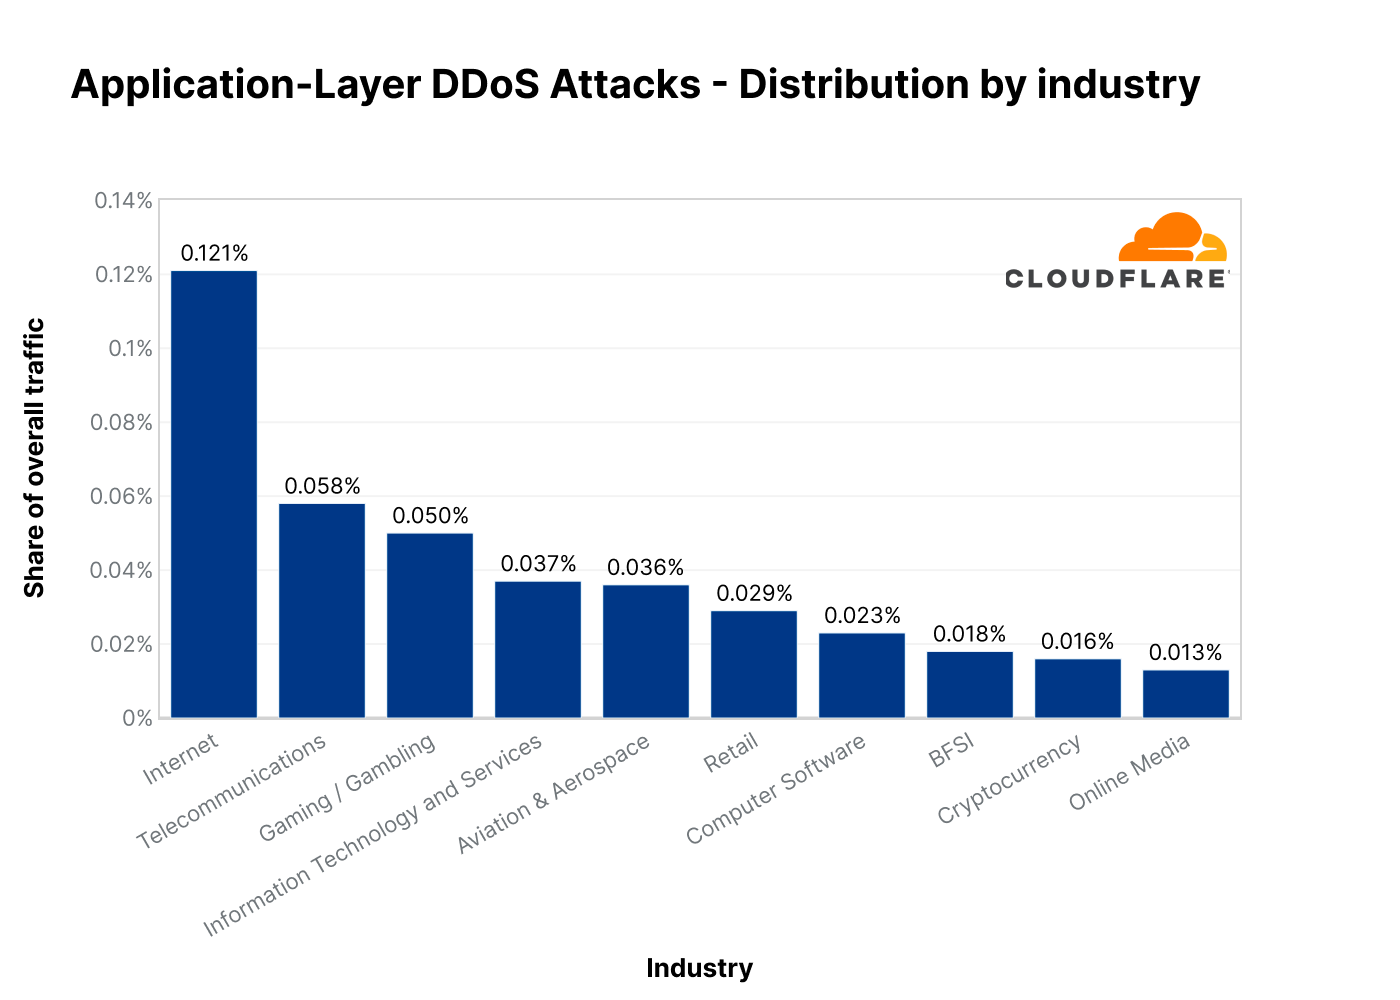
By bucketing the attacks by our customers’ industry of operation, we can see that HTTP applications operated by Internet companies were the most targeted in Q3. Attacks on the Internet industry increased by 131% QoQ and 300% YoY.
The second most attacked industry was the Telecommunications industry with an increase of 93% QoQ and 2,317% (!) YoY. In third place was the Gaming / Gambling industry with a more conservative increase of 17% QoQ and 36% YoY.
Bucketing attacks by our customers’ billing address gives us an understanding of which countries are more attacked. HTTP applications operated by US companies were the most targeted in Q3. US-based websites saw an increase of 60% QoQ and 105% YoY in attacks targeting them. After the US, was China with a 332% increase QoQ and an 800% increase YoY.
Looking at Ukraine, we can see that attacks targeting Ukrainian websites increased by 67% QoQ but decreased by 50% YoY. Furthermore, attacks targeting Russian websites increased by 31% QoQ and 2,400% (!) YoY.
In East Asia, we can see that attacks targeting Taiwanese companies increased by 200% QoQ and 60% YoY, and attacks targeting Japanese companies increased by 105% QoQ.
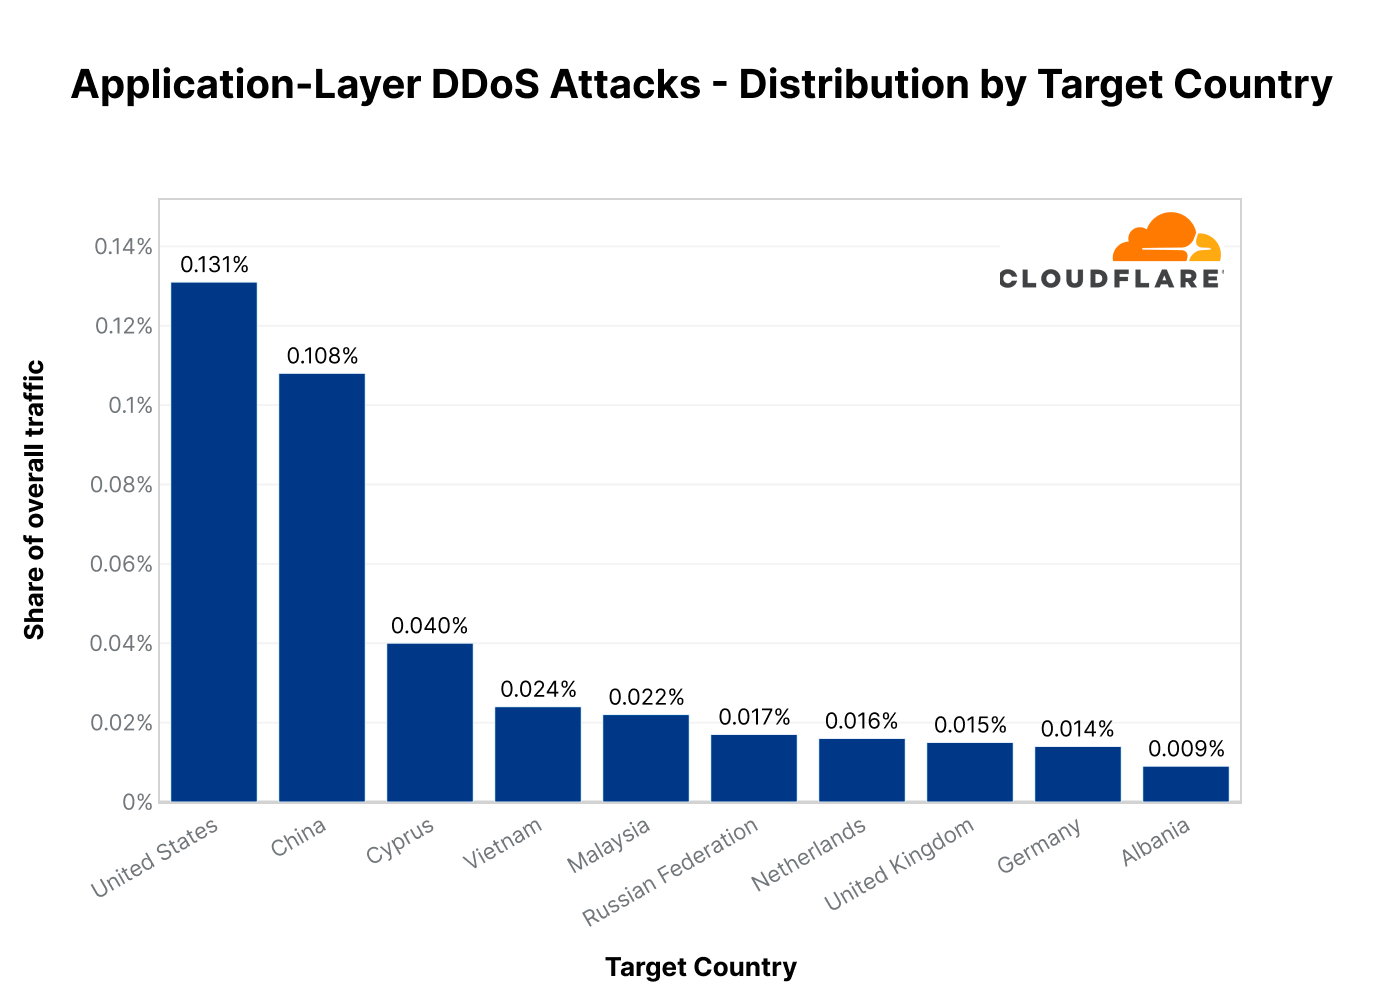
When we zoom in on specific countries, we can identify the below trends that may reveal interesting insights regarding the war in Ukraine and geopolitical events in East Asia:
In Ukraine, we see a surprising change in the attacked industries. Over the past two quarters, Broadcasting, Online Media and Publishing companies were targeted the most in what appeared to be an attempt to silence information and make it unavailable to civilians. However, this quarter, those industries dropped out of the top 10 list. Instead, the Marketing & Advertising industry took the lead (40%), followed by Education companies (20%), and Government Administration (8%).
In Russia, attacks on the Banking, Financial Services and Insurance (BFSI) industry continue to persist (25%). Be that as it may, attacks on the BFSI sector still decreased by 44% QoQ. In second place is the Events Services industry (20%), followed by Cryptocurrency (16%), Broadcast Media (13%), and Retail (11%). A significant portion of the attack traffic came from Germany-based IP addresses, and the rest were globally distributed.
In Taiwan, the two most attacked industries were Online Media (50%) and Internet (23%). Attacks to those industries were globally distributed indicating the usage of botnets.
In Japan, the most attacked industry was Internet/Media & Internet (52%), Business Services (12%), and Government – National (11%).
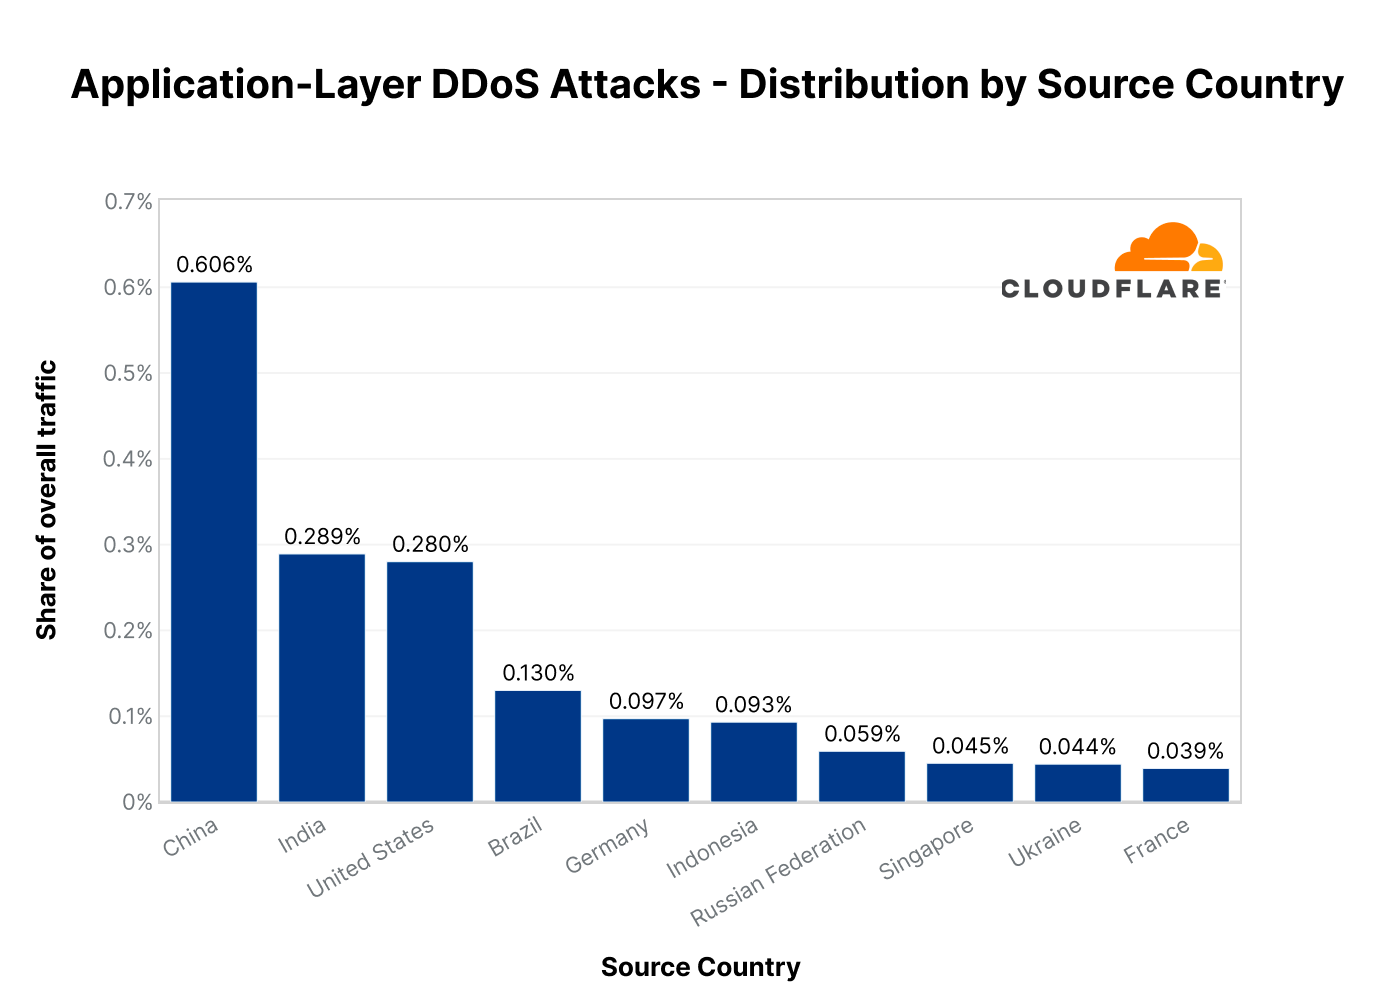
Before digging into specific source country metrics, it is important to note that while country of origin is interesting, it is not necessarily indicative of where the attacker is located. Oftentimes with DDoS attacks, they are launched remotely, and attackers will go to great lengths to hide their actual location in an attempt to avoid being caught. If anything, it is indicative of where botnet nodes are located. With that being said, by mapping the attacking IP address to their location, we can understand where attack traffic is coming from.
After two consecutive quarters, China replaced the US as the main source of HTTP DDoS attack traffic. In Q3, China was the largest source of HTTP DDoS attack traffic. Attack traffic from China-registered IP addresses increased by 29% YoY and 19% QoQ. Following China was India as the second-largest source of HTTP DDoS attack traffic — an increase of 61% YoY. After India, the main sources were the US and Brazil.
Looking at Ukraine, we can see that this quarter there was a drop in attack traffic originating from Ukrainian and Russian IP addresses — a decrease of 29% and 11% QoQ, respectively. However, YoY, attack traffic from within those countries still increased by 47% and 18%, respectively.
Another interesting data point is that attack traffic originating from Japanese IP addresses increased by 130% YoY.
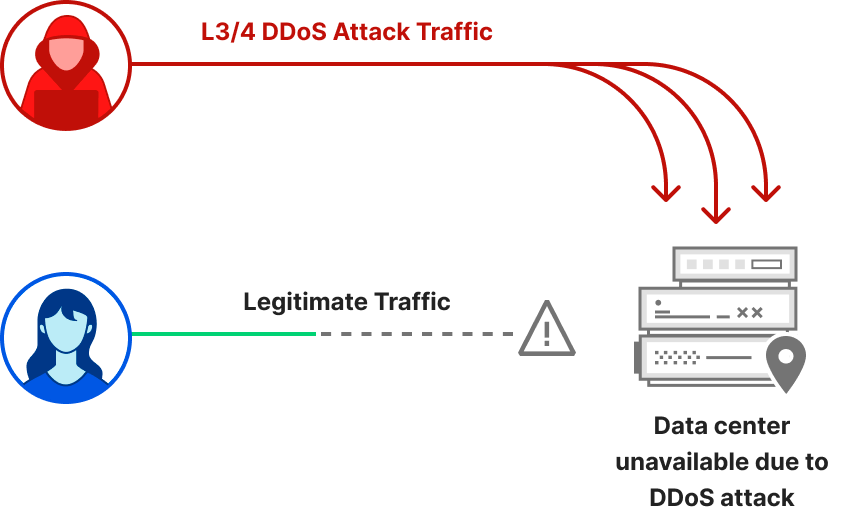
While application-layer attacks target the application (Layer 7 of the OSI model) running the service that end users are trying to access (HTTP/S in our case), network-layer attacks aim to overwhelm network infrastructure (such as in-line routers and servers) and the Internet link itself.
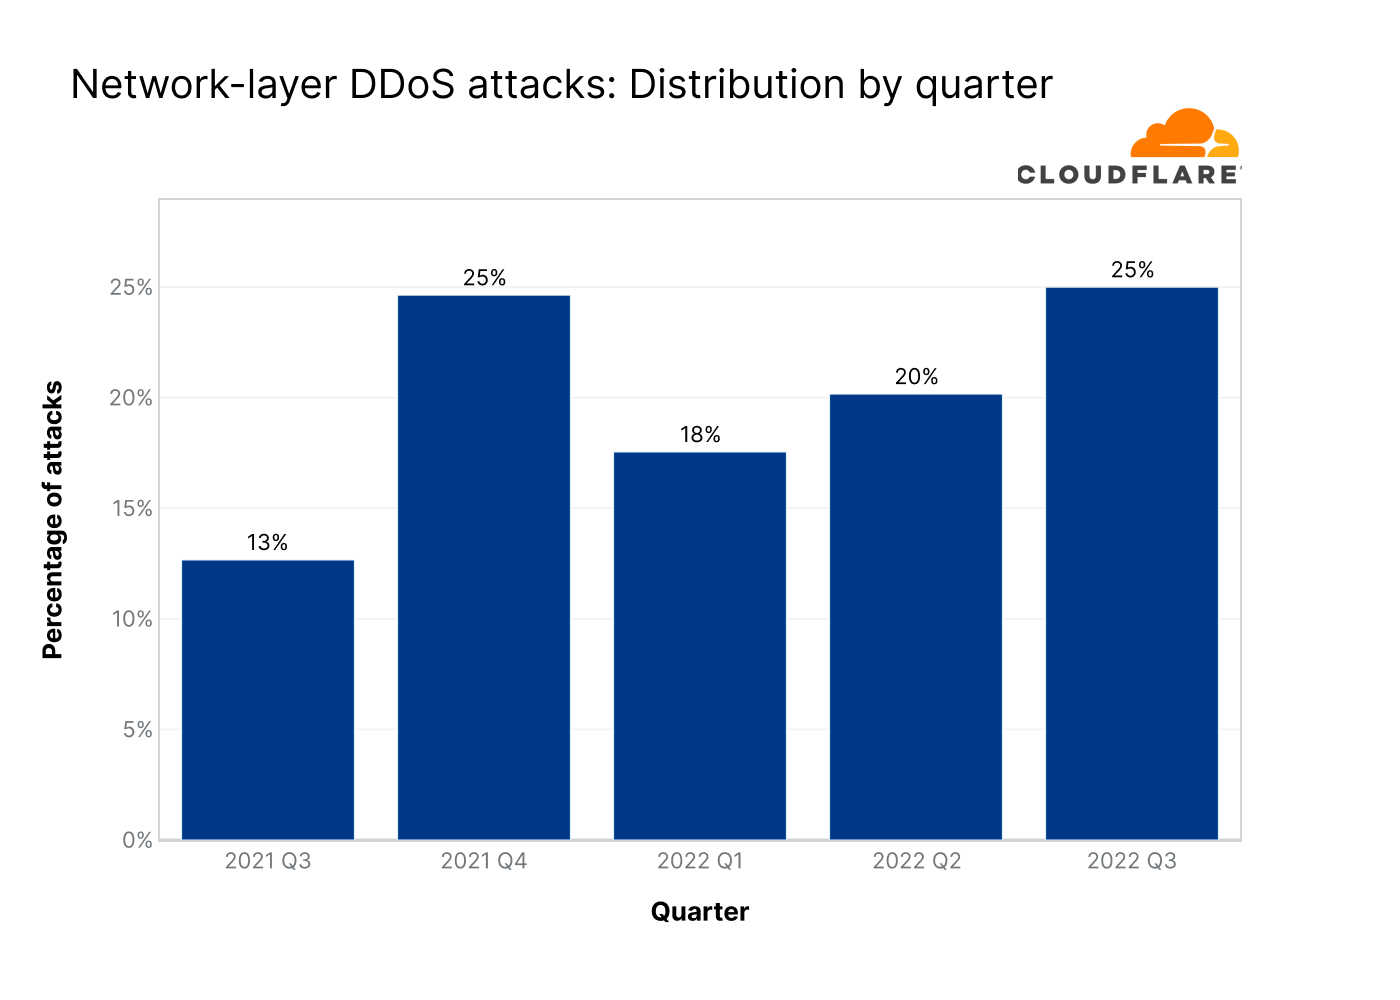
In Q3, we saw a large surge in L3/4 DDoS attacks — an increase of 97% YoY and a 24% QoQ. Furthermore, when we look at the graph we can see a clear trend, over the past three quarters, of an increase in attacks.
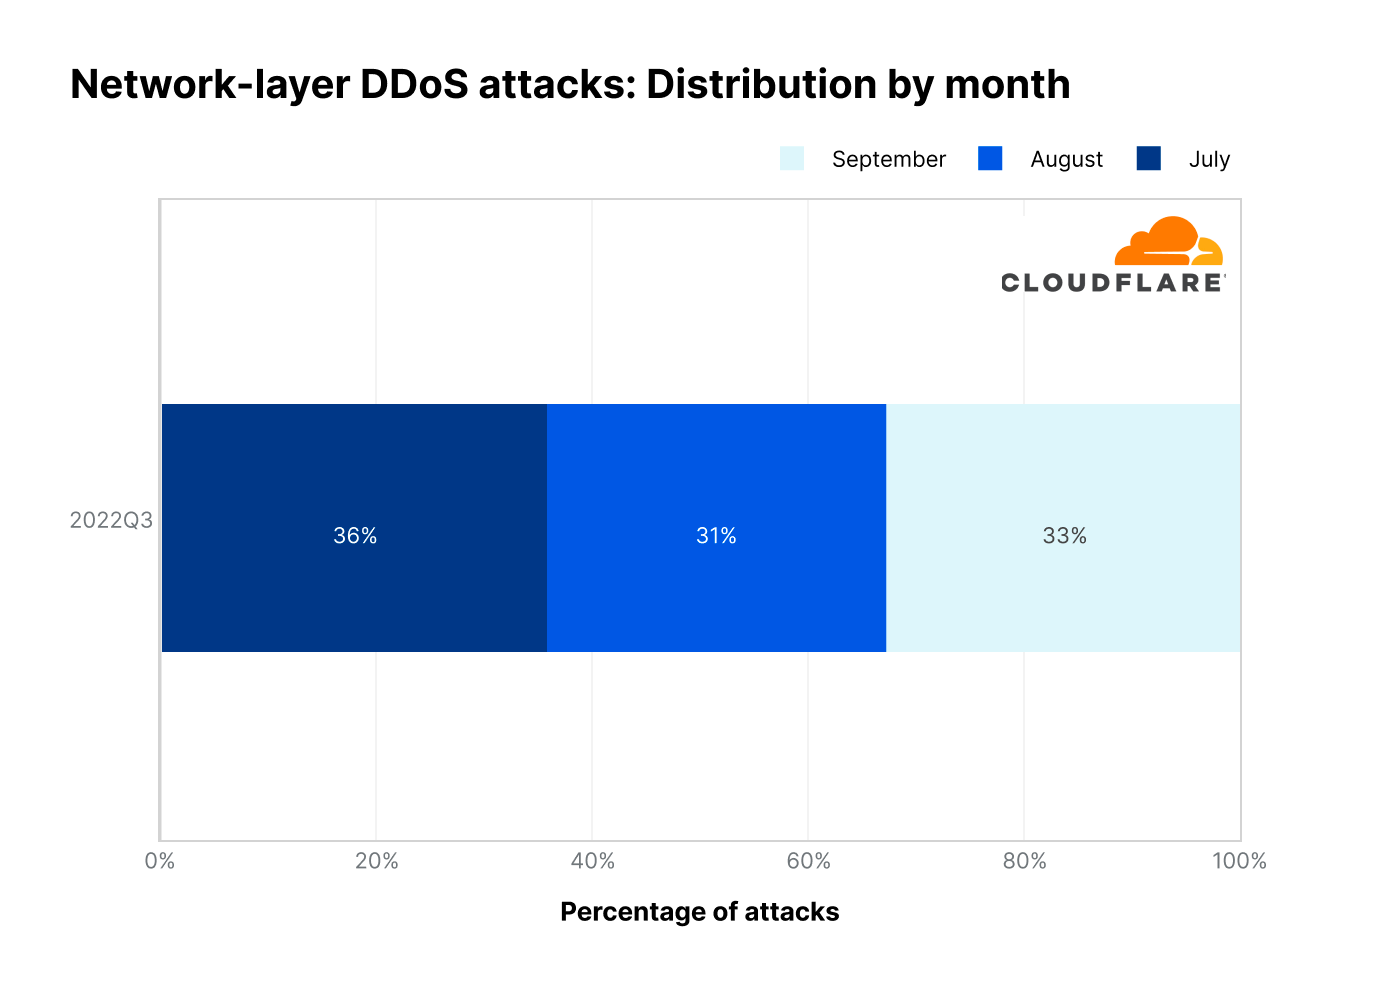
Drilling down into the quarter, it’s apparent that the attacks were, for the most part, evenly distributed throughout the quarter — with a slightly larger share for July.
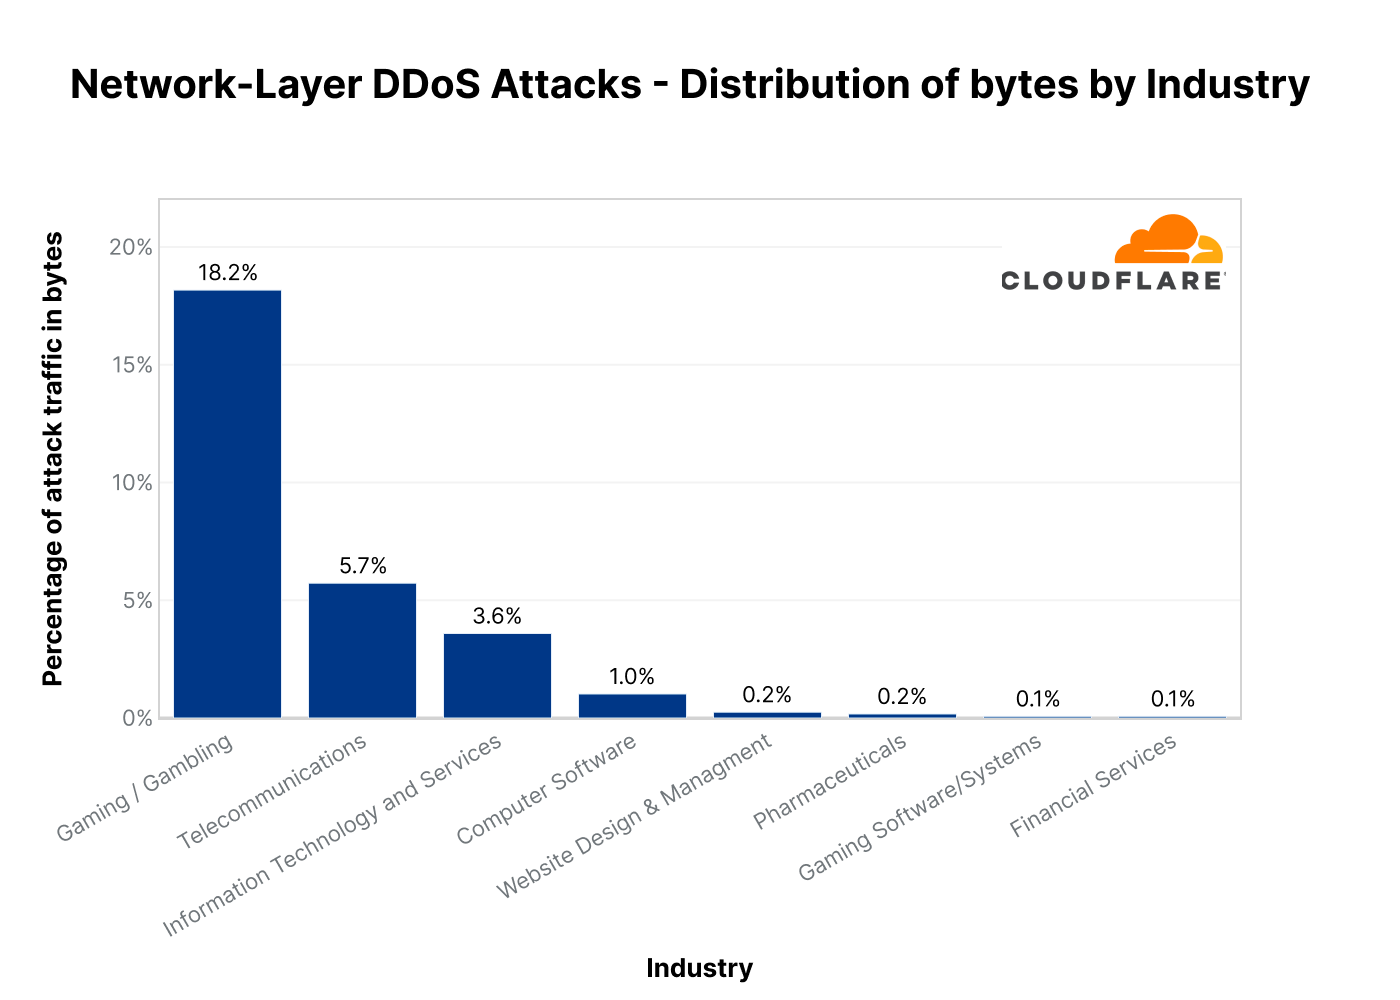
The Gaming / Gambling industry was hit by the most L3/4 DDoS attacks in Q3. Almost one out of every five bytes Cloudflare ingested towards Gaming / Gambling networks was part of a DDoS attack. This represents a whopping 381% increase QoQ.
The second most targeted industry was Telecommunications — almost 6% of bytes towards Telecommunications networks were part of DDoS attacks. This represents a 58% drop from the previous quarter where Telecommunications was the top most attacked industry by L3/4 DDoS attacks.
Following were the Information Technology and Services industry along with the Software industry. Both saw significant growth in attacks — 89% and 150% QoQ, respectively.
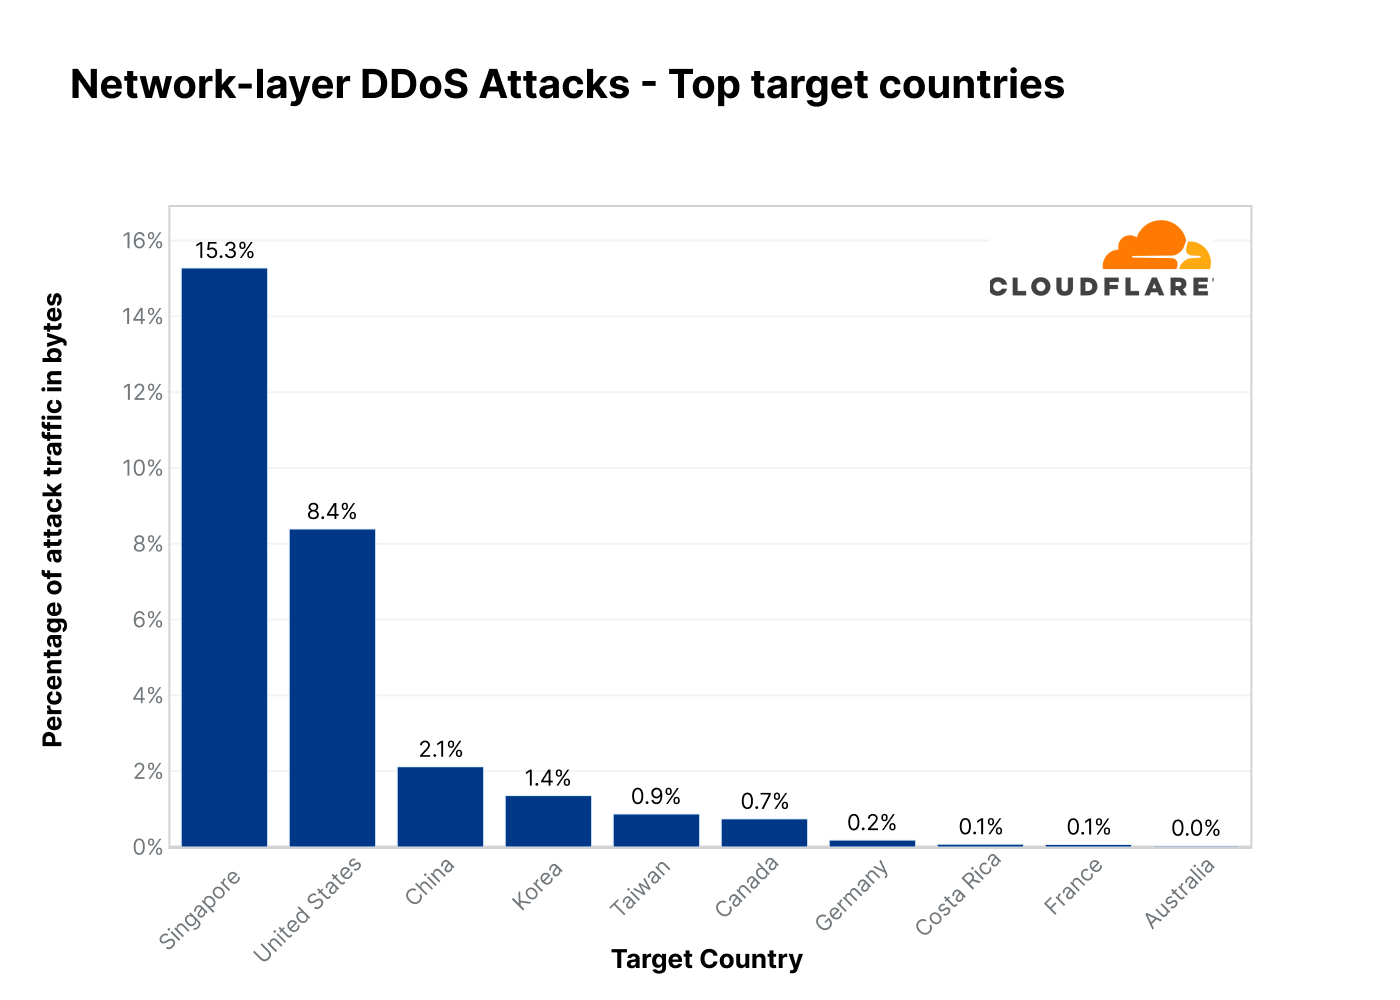
In Q3, Singapore-based companies saw the most L3/4 DDoS attacks — over 15% of all bytes to their networks were associated with a DDoS attack. This represents a dramatic 1,175% increase QoQ.
The US comes in second after a 45% decrease QoQ in attack traffic targeting US networks. In third, China, with a 62% QoQ increase. Attacks on Taiwan companies also increased by 200% QoQ.
In Q3, Cloudflare’s data centers in Azerbaijan saw the largest percentage of attack traffic. More than a third of all packets ingested there were part of a L3/4 DDoS attack. This represents a 44% increase QoQ and a huge 59-fold increase YoY.
Similarly, our data centers in Tunisia saw a dramatic increase in attack packets – 173x the amount in the previous year. Zimbabwe and Germany also saw significant increases in attacks.
Zooming into East Asia, we can see that our data centers in Taiwan saw an increase of attacks — 207% QoQ and 1,989% YoY. We saw similar numbers in Japan where attacks increased by 278% QoQ and 1,921% YoY.
Looking at Ukraine, we actually see a dip in the amount of attack packets we observed in our Ukraine-based and Russia-based data centers — 49% and 16% QoQ, respectively.

An attack vector is the method used to launch the attack or the method of attempting to achieve denial-of-service. With a combined share of 71%, SYN floods and DNS attacks remain the most popular DDoS attack vectors in Q3.
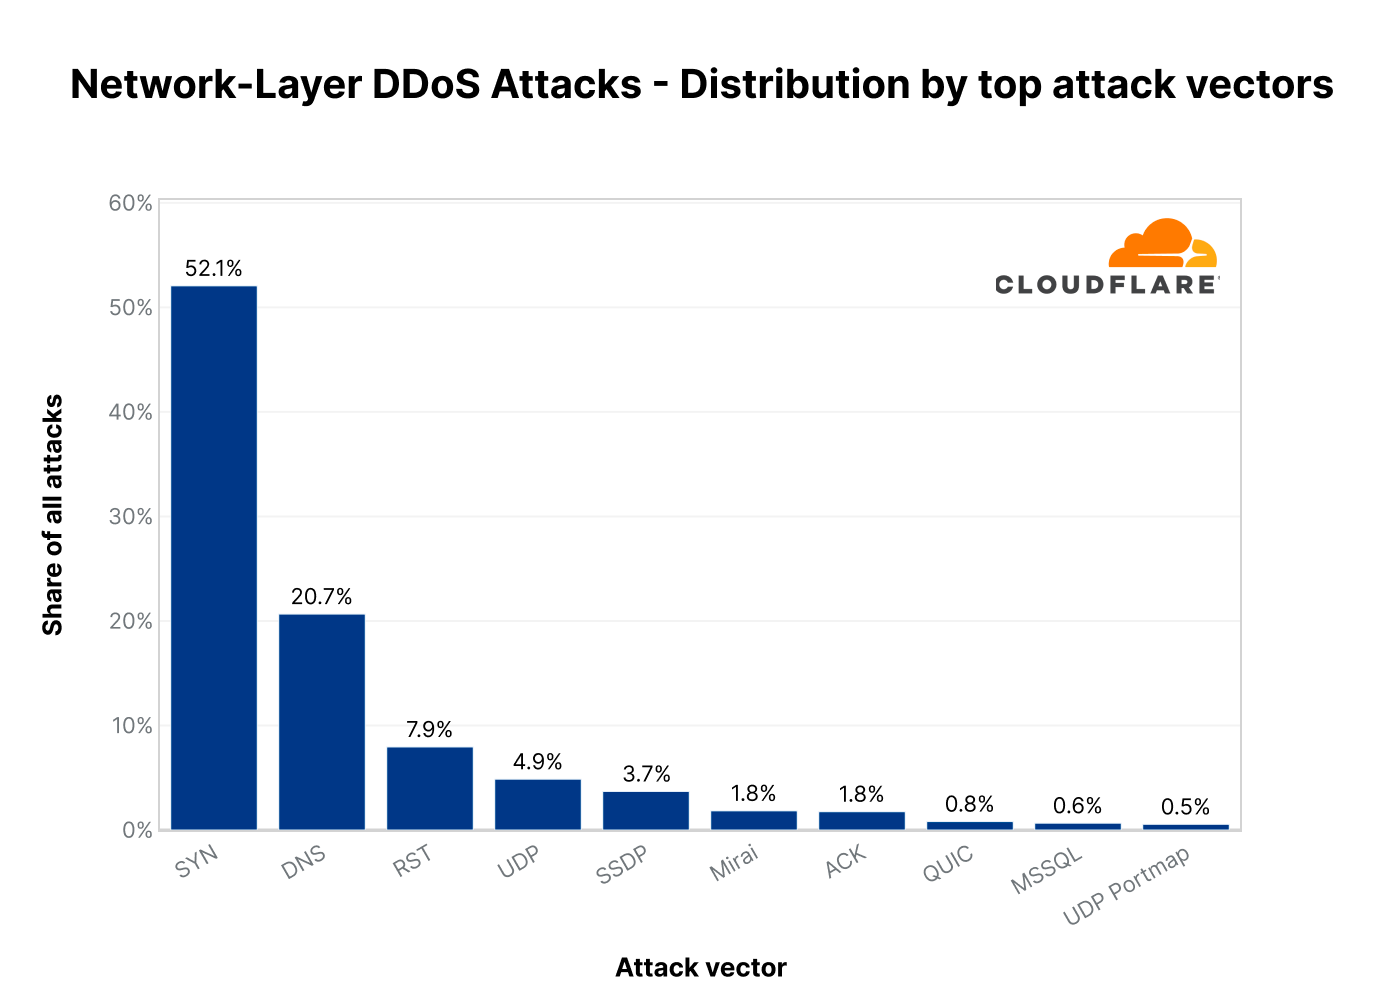
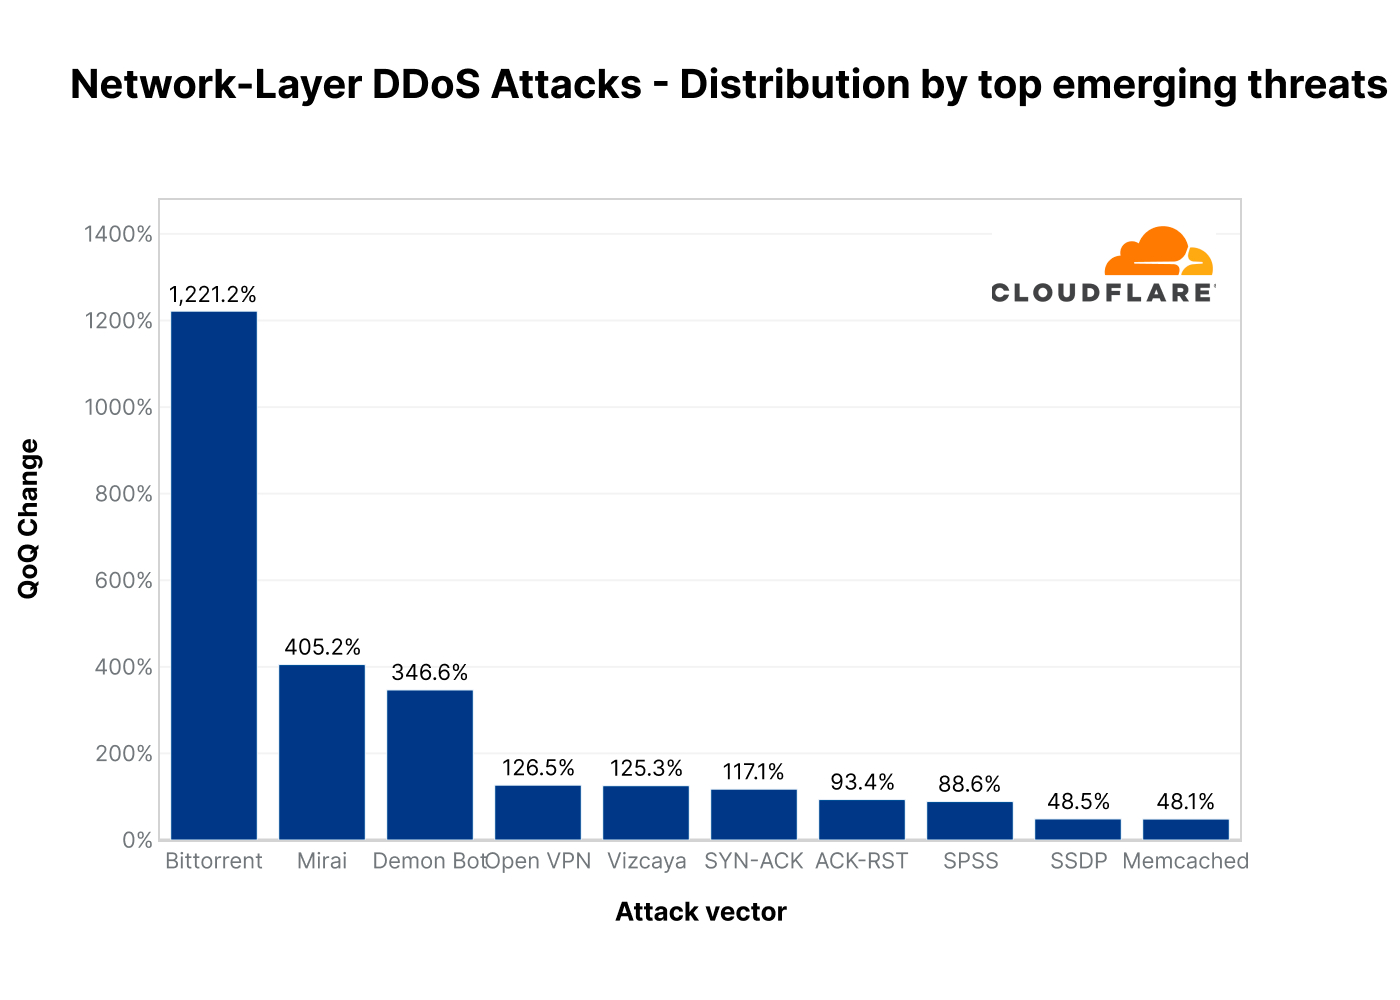
Last quarter, we saw a resurgence of attacks abusing the CHARGEN protocol, the Ubiquity Discovery Protocol, and Memcached reflection attacks. While the growth in Memcached DDoS attacks also slightly grew (48%), this quarter, there was a more dramatic increase in attacks abusing the BitTorrent protocol (1,221%), as well as attacks launched by the Mirai botnet and its variants.
BitTorrent DDoS attacks increased by 1,221% QoQ
The BitTorrent protocol is a communication protocol that’s used for peer to peer file sharing. To help the BitTorrent clients find and download the files efficiently, BitTorrent clients may use BitTorrent Trackers or Distributed Hash Tables (DHT) to identify the peers that are seeding the desired file. This concept can be abused to launch DDoS attacks. A malicious actor can spoof the victim’s IP address as a seeder IP address within Trackers and DHT systems. Then clients would request the files from those IPs. Given a sufficient number of clients requesting the file, it can flood the victim with more traffic than it can handle.
Mirai DDoS attacks increased by 405% QoQ
Mirai is malware that infects smart devices that run on ARC processors, turning them into a network of bots that can be used to launch DDoS attacks. This processor runs a stripped-down version of the Linux operating system. If the default username-and-password combo is not changed, Mirai is able to log in to the device, infect it, and take over. The botnet operator can instruct the botnet to launch a flood of UDP packets at the victim’s IP address to bombard them.
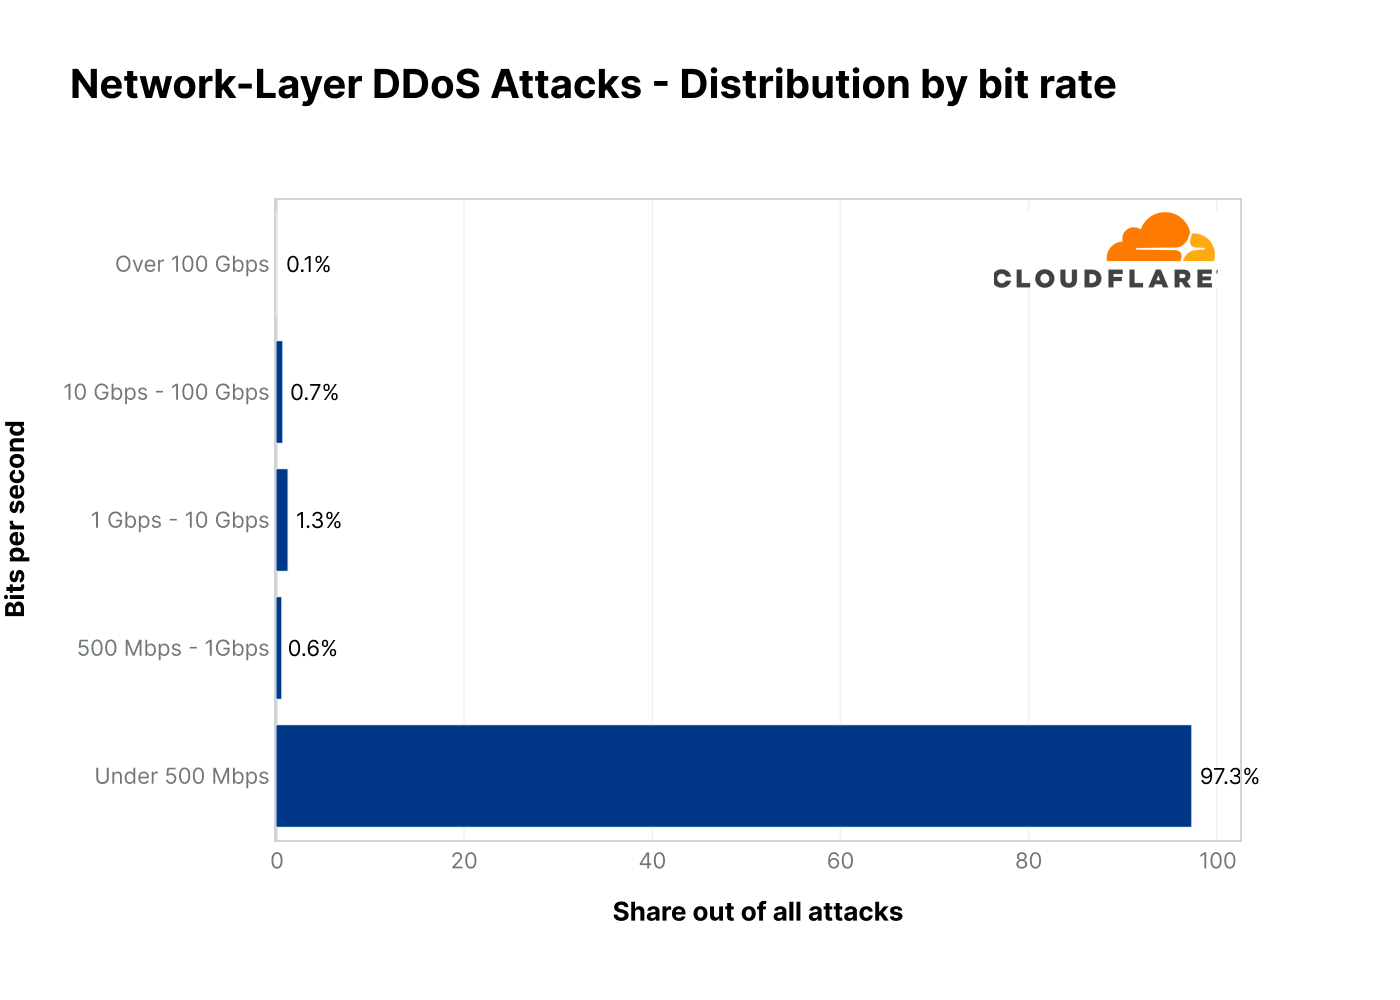
While Terabit-strong attacks are becoming more frequent, they are still the outliers. The majority of attacks are tiny (in terms of Cloudflare scale). Over 95% of attacks peaked below 50,000 packets per second (pps) and over 97% below 500 Megabits per second (Mbps). We call this “cyber vandalism”.
What is cyber vandalism? As opposed to “classic” vandalism where the purpose is to cause deliberate destruction of or damage to public or private physical property — such as graffiti on the side of a building — in the cyberworld, cyber vandalism is the act of causing deliberate damage to Internet properties. Today the source codes for various botnets are available online and there are a number of free tools that can be used to launch a flood of packets. By directing those tools to Internet properties, any script-kid can use those tools to launch attacks against their school during exam season or any other website they desire to take down or disrupt. This is as opposed to organized crime, Advanced Persistent Threat actors, and state-level actors that can launch much larger and sophisticated attacks.
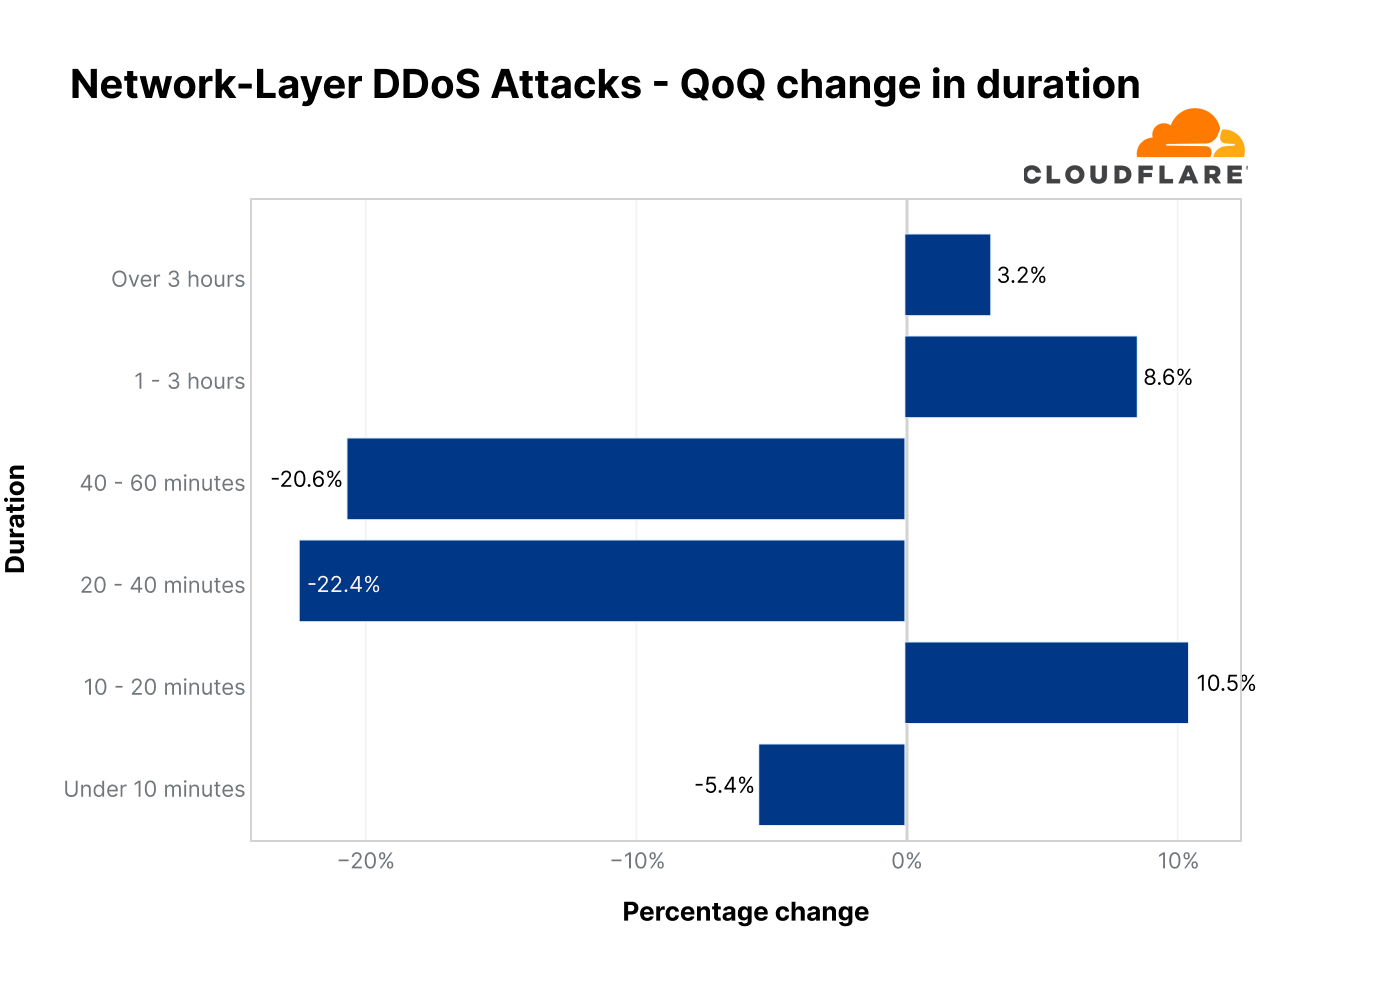
Similarly, most of the attacks are very short and end within 20 minutes (94%). This quarter we did see an increase of 9% in attacks of 1-3 hours, and a 3% increase in attacks over 3 hours — but those are still the outliers.
Even with the largest attacks, such as the 2.5 Tbps attack we mitigated earlier this quarter, and the 26M request per second attack we mitigated back in the summer, the peak of the attacks were short-lived. The entire 2.5 Tbps attack lasted about 2 minutes, and the peak of the 26M rps attack only 15 seconds. This emphasizes the need for automated, always-on solutions. Security teams can’t respond quick enough. By the time the security engineer looks at the PagerDuty notification on their phone, the attack has subsided.
Attacks may be initiated by humans, but they are executed by bots — and to play to win, you must fight bots with bots. Detection and mitigation must be automated as much as possible, because relying solely on humans puts defenders at a disadvantage. Cloudflare’s automated systems constantly detect and mitigate DDoS attacks for our customers, so they don’t have to.
Over the years, it has become easier, cheaper, and more accessible for attackers and attackers-for-hire to launch DDoS attacks. But as easy as it has become for the attackers, we want to make sure that it is even easier – and free – for defenders of organizations of all sizes to protect themselves against DDoS attacks of all types. We’ve been providing unmetered and unlimited DDoS protection for free to all of our customers since 2017 — when we pioneered the concept.
Cloudflare’s mission is to help build a better Internet. A better Internet is one that is more secure, faster, and reliable for everyone – even in the face of DDoS attacks.
Post Syndicated from Ben Austin original https://blog.rapid7.com/2022/10/12/real-time-risk-mitigation-in-google-cloud-platform/
With Google Cloud Next happening this week, there’s been some recent water cooler talk – okay, informal, ad hoc Zoom calls – where discussions about what makes Google Cloud Platform (GCP) unique when it comes to security. A few specific differences have popped up here and there (default data encryption, the way IAM is handled, etc.), but, generally speaking, many of the principles that apply to all other cloud providers apply to GCP environments.
For one, due to the speed and scale of these environments, it’s simultaneously very difficult and extremely critical to maintain an up-to-date inventory of the state of all resources in your environment. This means constantly monitoring your environment for resources being created, deleted, or modified in as close to real time as possible.
And in an effort to avoid ambiguity or hide behind marketing buzz terms, when I’m referring to “real time” here, I’m talking about sub 5-minute intervals based on activity happening in the environment. This is not to be confused with “near real time” approaches some vendors tout, which, in reality, still only pulls in data once or twice a day based on a static schedule.
In GCP, like in AWS, Azure, and all other cloud environments, simply getting a snapshot once a day to identify misconfigurations, vulnerabilities, or suspicious behaviors like you might with an on-prem data center just isn’t a scalable strategy. It’s a common cliche, but the ephemeral nature and rate of change in public cloud environments makes that kind of scanning strategy extremely ineffective when it comes to monitoring, analyzing, and eliminating actual risk in a cloud environment.
Let me lay out a couple examples where this kind of real-time monitoring can provide significant, potentially necessary, value to security teams working to make their cloud risk management programs more effective.
As an example, say a developer is in a GCP project associated with your company’s revenue-generating application and they spin up a Cloud Storage instance that is, whether mistakenly or maliciously, open to the public internet.
If your security team is reliant on a scan to happen 12 hours later to get visibility into this activity, your organization will constantly be left open to significant risk. Take away the hyperbole here and assume it’s a much smaller risk or compliance violation. Even in that situation, your team is still working from behind and, presumably, almost always facing some level of stress about what issues are out there in the environment that they won’t know about for another 12-18 hours.
Worst of all, with this type of scanning you’re generally just getting a point-in-time snapshot of the environment and usually don’t know who made the change or how long ago it happened. This makes it much more difficult and time consuming for your team to actually assess the risk or get their hands on the right information to make an informed decision about how the situation should be addressed.
When a team is working with real-time data, however, they can be much more diligent and confident that they’re prioritizing the right issues at any given moment, with all the necessary context about who made the change and when it occurred. This not only helps teams stay ahead of issues and reduce the risk of a breach in their environment, but also helps keep individuals and teams feeling positive about the impact that the program is having on the organization.
Building off of the previous example, it’s not only that teams can’t respond to risk they haven’t been notified of, it’s also that any automated response workflows your team may have built out to be more efficient are significantly less effective when they’re triggered by hours-old data. A 12-hour delay in an automation workflow all but eliminates the value of the automation itself, and it can actually cause headaches and confusion that detract from your team’s efficiency, rather than improving it (more on this in the next example).
In contrast, if you’re able to detect risky changes to your environment as they happen, you can automatically respond to that issue as it happens. In the case of this all being a mistake caused by a developer working a little too quickly, you’re able to automatically notify them of their error within a matter of minutes, likely while they’re still working within that project. Giving your development team this kind of feedback in the moment, rather than forcing them to context switch and go back into the project to fix the error a day later, is an excellent way to build stronger relationships and rapport with that team.
In the more rare case that this is indeed a malicious internal or external actor, enabling your automated remediation workflows to kick into gear within seconds and potentially stop the behavior could mean the difference between a minor incident and a breach requiring public disclosure from your organization.
Speaking of relationships with the development team (sorry, #DevSecOps), I can almost guarantee that working with data from scans or snapshots that occur every 12 or 24 hours in your cloud will cause friction between your two teams. Whether it’s tied to manual identification of risky resources or automated workflows notifying them of a non-compliant asset, working with stale data will inevitably lead to false positives that will both annoy and distract your already overburdened development team.
Take the example highlighted above, but instead, let’s say the developer actually spun up that Cloud Storage instance for a short amount of time in a dev instance with no actual customer data as part of a testing exercise. By the time your team gets visibility into this and either reaches out manually or has some automated notification sent to the developer, that instance could have already been deleted for hours. Now your team is looking at one set of old data and seeing an issue, meanwhile the developer is insisting that the storage container doesn’t even exist anymore. As mentioned above, this is going to cause headaches and frustration for both parties, and cause your team to lose credibility with the dev team.
At this point, you can probably guess where this is going next. With real-time monitoring in your environment this situation can be avoided altogether because your team will be looking at the same up-to-date information, and your team will be able to see that the storage container was shut down or removed from the project rather than spending time chasing down a false positive.
Earlier this month we released event-driven harvesting for GCP in InsightCloudSec. This agentless, real-time monitoring helps your security team achieve every one of the benefits outlined above while also avoiding API rate limiting. In addition, we’ve recently added GCP CIS Benchmarks v1.3.0, added GCP threat findings into our console, and added support for Google Directory to give visibility into IAM factors such as user last login, MFA status, group association and more.
If you want to learn more about how Rapid7 can help you secure Google Cloud Platform, or any other public cloud environment, sign up for our live bi-weekly demo of InsightCloudSec.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=QajRLyvCH8Y
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/10/recovering-passwords-by-measuring-residual-heat.html
Researchers have used thermal cameras and ML guessing techniques to recover passwords from measuring the residual heat left by fingers on keyboards. From the abstract:
We detail the implementation of ThermoSecure and make a dataset of 1,500 thermal images of keyboards with heat traces resulting from input publicly available. Our first study shows that ThermoSecure successfully attacks 6-symbol, 8-symbol, 12-symbol, and 16-symbol passwords with an average accuracy of 92%, 80%, 71%, and 55% respectively, and even higher accuracy when thermal images are taken within 30 seconds. We found that typing behavior significantly impacts vulnerability to thermal attacks, where hunt-and-peck typists are more vulnerable than fast typists (92% vs 83% thermal attack success if performed within 30 seconds). The second study showed that the keycaps material has a statistically significant effect on the effectiveness of thermal attacks: ABS keycaps retain the thermal trace of users presses for a longer period of time, making them more vulnerable to thermal attacks, with a 52% average attack accuracy compared to 14% for keyboards with PBT keycaps.
“ABS” is Acrylonitrile Butadiene Styrene, which some keys are made of. Others are made of Polybutylene Terephthalate (PBT). PBT keys are less vulnerable.
But, honestly, if someone can train a camera at your keyboard, you have bigger problems.
News article.
Post Syndicated from original https://xkcd.com/2684/
Post Syndicated from original https://lwn.net/Articles/910740/
The kernel’s Bugzilla
instance is largely unloved and ignored, at least as a bug-reporting
tool for the bulk of the upstream kernel. At the recent Maintainers Summit,
Bugzilla was discussed during the regression-handling session led by Thorsten
Leemhuis. In a followup to that discussion, Leemhuis posted
some ideas for improving the state of bugzilla.kernel.org to the
ksummit-discuss mailing list recently; the resulting discussion helped
clarify a number of problem areas for it—and for the Bugzilla tool itself.
Post Syndicated from Биволъ original https://bivol.bg/%D0%BF%D0%BE%D1%80%D0%BE%D1%8F%D1%82-%D0%BC%D0%B0%D0%B3%D0%B8%D1%81%D1%82%D1%80%D0%B0%D0%BB%D0%B8%D1%82%D0%B5-%D0%B2-%D0%B3%D0%BE%D1%80%D0%B0%D1%82%D0%B0.html

“Никой няма да забрави картините с пороя, удавил на втори септември трите карловски села – Каравелово, Богдан и Слатина. И трите са в подножието на планината – Средна гора. Истински…
Post Syndicated from Rohit Bansal original https://aws.amazon.com/blogs/big-data/improve-federated-queries-with-predicate-pushdown-in-amazon-athena/
In modern data architectures, it’s common to store data in multiple data sources. However, organizations embracing this approach still need insights from their data and require technologies that help them break down data silos. Amazon Athena is an interactive query service that makes it easy to analyze structured, unstructured, and semi-structured data stored in Amazon Simple Storage Service (Amazon S3) in addition to relational, non-relation, object, and custom data sources through its query federation capabilities. Athena is serverless, so there’s no infrastructure to manage, and you only pay for the queries that you run.
Organizations building a modern data architecture want to query data in-place from purpose-built data stores without building complex extract, transform, and load (ETL) pipelines. Athena’s federated query feature allows organizations to achieve this and makes it easy to:
However, when querying and joining huge amounts of data from different data stores, it’s important for queries to run quickly, at low cost, and without impacting source systems. Predicate pushdown is supported by many query engines and is a technique that can drastically reduce query processing time by filtering data at the source early in the processing workflow. In this post, you’ll learn how predicate pushdown improves query performance and how you can validate when Athena applies predicate pushdown to federated queries.
The key benefits of predicate pushdown are as follows:
Let’s explore a real-world scenario to understand when predicate pushdown is applied to federated queries in Athena.
Imagine a hypothetical ecommerce company with data stored in
Record counts for these tables are as follows.
| Data Store | Table Name | Number of Records | Description |
| Amazon Redshift | Catalog_Sales |
4.3 billion | Current and historical Sales data fact Table |
| Amazon Redshift | Date_dim |
73,000 | Date Dimension table |
| DynamoDB | Part |
20,000 | Realtime Parts and Inventory data |
| DynamoDB | Partsupp |
80,000 | Realtime Parts and supplier data |
| Aurora MySQL | Supplier |
1,000 | Latest Supplier transactions |
| Aurora MySQL | Customer |
15,000 | Latest Customer transactions |
Our requirement is to query these sources individually and join the data to track pricing and supplier information and compare recent data with historical data using SQL queries with various filters applied. We’ll use Athena federated queries to query and join data from these sources to meet this requirement.
The following diagram depicts how Athena federated queries use data source connectors run as Lambda functions to query data stored in sources other than Amazon S3.

When a federated query is submitted against a data source, Athena invokes the data source connector to determine how to read the requested table and identify filter predicates in the WHERE clause of the query that can be pushed down to the source. Applicable filters are automatically pushed down by Athena and have the effect of omitting unnecessary rows early in the query processing workflow and improving overall query execution time.
Let’s explore three use cases to demonstrate predicate pushdown for our ecommerce company using each of these services.
As a prerequisite, review Using Amazon Athena Federated Query to know more about Athena federated queries and how to deploy these data source connectors.
In our first scenario, we run an Athena federated query on Amazon Redshift by joining its Catalog_sales and Date_dim tables. We do this to show the number of sales orders grouped by order date. The following query gets the information required and takes approximately 14 seconds scanning approximately 43 MB of data:
Athena pushes the following filters to the source for processing:
cs_sold_date_sk between 2450815 and 2450822 for the Catalog_Sales table in Amazon Redshift.d_date_sk between 2450815 and 2450822; because of the join l.cs_sold_date_sk=d_date_sk in the query, the Date_dim table is also filtered at the source, and only filtered data is moved from Amazon Redshift to Athena.Let’s analyze the query plan by using recently released visual explain tool to confirm the filter predicates are pushed to the data source:

As shown above (only displaying the relevant part of the visual explain plan), because of the predicate pushdown, the Catalog_sales and Date_dim tables have filters applied at the source. Athena processes only the resulting filtered data.
Using the Athena console, we can see query processing details using the recently released query stats to interactively explore processing details with predicate pushdown at the query stage:

Displaying only the relevant query processing stages, Catalog_sales table has approximately 4.3 billion records, and Date_dim has approximately 73,000 records in Amazon Redshift. Only 11 million records from the Catalog_sales (Stage 4) and 8 records from the Date_dim (Stage 5) are passed from source to Athena, because the predicate pushdown pushes query filter conditions to the data sources. This filters out unneeded records at the source, and only brings the required rows to Athena.
Using predicate pushdown resulted in scanning 99.75% less data from Catalog_sales and 99.99% less data from Date_dim. This results in a faster query runtime and lower cost.
In our second use case, we run an Athena federated query on Aurora MySQL and Amazon Redshift data stores. This query joins the Catalog_sales and Date_dim tables in Amazon Redshift with the Customer table in the Aurora MySQL database to get the total number of orders with the total amount spent by each customer for the first week in January 1998 for the market segment of AUTOMOBILE. The following query gets the information required and takes approximately 35 seconds scanning approximately 337 MB of data:
Athena pushes the following filters to the data sources for processing:
cs_sold_date_sk between 2450815 and 2450822 for the Catalog_Sales table in Amazon Redshift.d_date_sk between 2450815 and 2450822; because of the join l.cs_sold_date_sk=d_date_sk in the query, the Date_dim table is also filtered at the source (Amazon Redshift) and only filtered data is moved from Amazon Redshift to Athena.c_mktsegment = 'AUTOMOBILE' for the Customer table in the Aurora MySQL database.Now let’s consult the visual explain plan for this query to show the predicate pushdown to the source for processing:
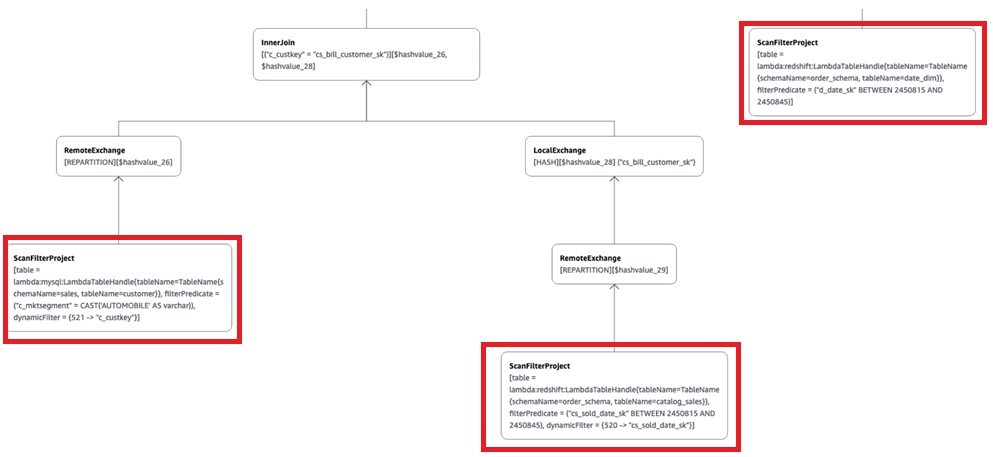
As shown above (only displaying the relevant part of the visual explain plan), because of the predicate pushdown, Catalog_sales and Date_dim have the query filter applied at the source (Amazon Redshift), and the customer table has the market segment AUTOMOBILE filter applied at the source (Aurora MySQL). This brings only the filtered data to Athena.
As before, we can see query processing details using the recently released query stats to interactively explore processing details with predicate pushdown at the query stage:
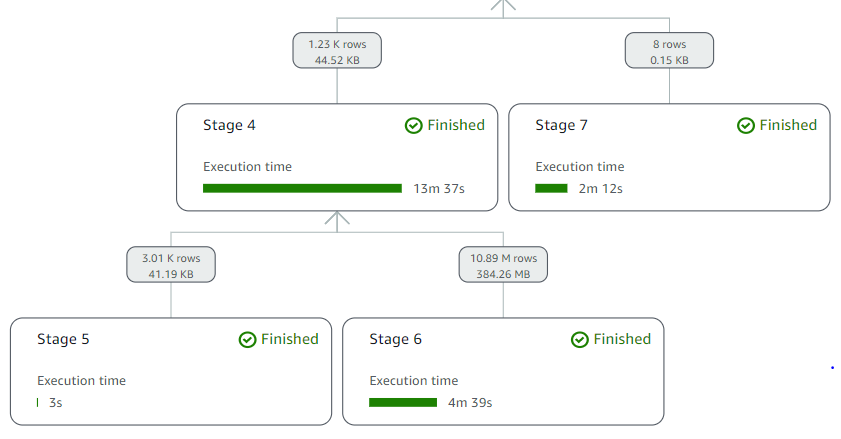
Displaying only the relevant query processing stages, Catalog_sales has 4.3 billion records, Date_Dim has 73,000 records in Amazon Redshift, and Customer has 15,000 records in Aurora MySQL. Only 11 million records from Catalog_sales (Stage 6), 8 records from Date_dim (Stage 7), and 3,000 records from Customer (Stage 5) are passed from the respective sources to Athena because the predicate pushdown pushes query filter conditions to the data sources. This filters out unneeded records at the source and only brings the required rows to Athena.
Here, predicate pushdown resulted in scanning 99.75% less data from Catalog_sales, 99.99% less data from Date_dim, and 79.91% from Customer. Furthermore, this results in a faster query runtime and reduced cost.
For our third use case, we run an Athena federated query on Aurora MySQL, Amazon Redshift, and DynamoDB data stores. This query joins the Part and Partsupp tables in DynamoDB, the Catalog_sales and Date_dim tables in Amazon Redshift, and the Supplier and Customer tables in Aurora MySQL to get the quantities available at each supplier for orders with the highest revenue during the first week of January 1998 for the market segment of AUTOMOBILE and parts manufactured by Manufacturer#1.
The following query gets the information required and takes approximately 33 seconds scanning approximately 428 MB of data in Athena:
Athena pushes the following filters to the data sources for processing:
cs_sold_date_sk between 2450815 and 2450822 for the Catalog_Sales table in Amazon Redshift.d_date_sk between 2450815 and 2450822; because of the join l.cs_sold_date_sk=d_date_sk in the query, the Date_dim table is also filtered at the source and only filtered data is moved from Amazon Redshift to Athena.c_mktsegment = 'AUTOMOBILE' for the Customer table in the Aurora MySQL database.p.p_mfgr='Manufacturer#1' for the Part table in DynamoDB.Now let’s run the explain plan for this query to confirm predicates are pushed down to the source for processing:
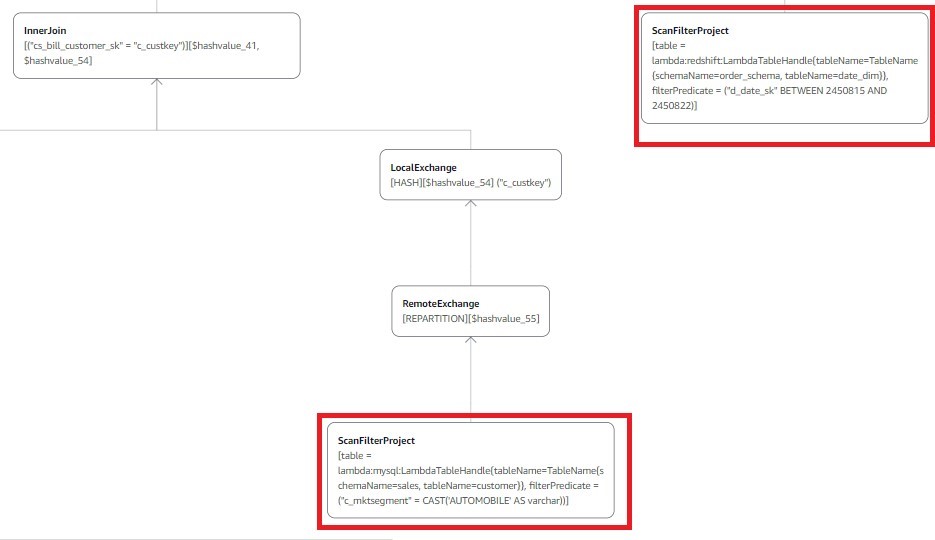

As shown above (displaying only the relevant part of the plan), because of the predicate pushdown, Catalog_sales and Date_dim have the query filter applied at the source (Amazon Redshift), the Customer table has the market segment AUTOMOBILE filter applied at the source (Aurora MySQL), and the Part table has the part manufactured by Manufacturer#1 filter applied at the source (DynamoDB).
We can analyze query processing details using the recently released query stats to interactively explore processing details with predicate pushdown at the query stage:

Displaying only the relevant processing stages, Catalog_sales has 4.3 billion records, Date_Dim has 73,000 records in Amazon Redshift, Customer has 15,000 records in Aurora MySQL, and Part has 20,000 records in DynamoDB. Only 11 million records from Catalog_sales (Stage 5), 8 records from Date_dim (Stage 9), 3,000 records from Customer (Stage 8), and 4,000 records from Part (Stage 4) are passed from their respective sources to Athena, because the predicate pushdown pushes query filter conditions to the data sources. This filters out unneeded records at the source, and only brings the required rows from the sources to Athena.
When using Athena to query your data sources, consider the following:
WHERE log2(col)<10).In this post, we demonstrated three federated query scenarios on Aurora MySQL, Amazon Redshift, and DynamoDB to show how predicate pushdown improves federated query performance and reduces cost and how you can validate when predicate pushdown occurs. If the federated data source supports parallel scans, then predicate pushdown makes it possible to achieve performance that is close to the performance of Athena queries on data stored in Amazon S3. You can utilize the patterns and recommendations outlined in this post when querying supported data sources to improve overall query performance and minimize data scanned.
 Rohit Bansal is an Analytics Specialist Solutions Architect at AWS. He has nearly two decades of experience helping customers modernize their data platforms. He is passionate about helping customers build scalable, cost-effective data and analytics solutions in the cloud. In his spare time, he enjoys spending time with his family, travel, and road cycling.
 Ruchir Tripathi is a Senior Analytics Solutions Architect aligned to Global Financial Services at AWS. He is passionate about helping enterprises build scalable, performant, and cost-effective solutions in the cloud. Prior to joining AWS, Ruchir worked with major financial institutions and is based out of New York Office.
Post Syndicated from Moustafa Mahmoud original https://aws.amazon.com/blogs/big-data/land-data-from-databases-to-a-data-lake-at-scale-using-aws-glue-blueprints/
To build a data lake on AWS, a common data ingestion pattern is to use AWS Glue jobs to perform extract, transform, and load (ETL) data from relational databases to Amazon Simple Storage Service (Amazon S3). A project often involves extracting hundreds of tables from source databases to the data lake raw layer. And for each source table, it’s recommended to have a separate AWS Glue job to simplify operations, state management, and error handling. This approach works perfectly with a small number of tables. However, with hundreds of tables, this results in hundreds of ETL jobs, and managing AWS Glue jobs at this scale may pose an operational challenge if you’re not yet ready to deploy using a CI/CD pipeline. Instead, we tackle this issue by decoupling the following:
In this post, you will learn how to handle data lake landing jobs deployment in a standardized way—by maintaining a JSON file with table names and a few parameters (for example, a workflow catalog). AWS Glue workflows are created and updated after manually running the resources deployment flow in Step Functions. You can further customize the AWS Glue blueprints to make your own multi-step data pipelines to move data to downstream layers and purpose-built analytics services (example use cases include partitioning or importing to an Amazon DynamoDB table).
The following diagram illustrates the solution architecture, which contains two major areas:
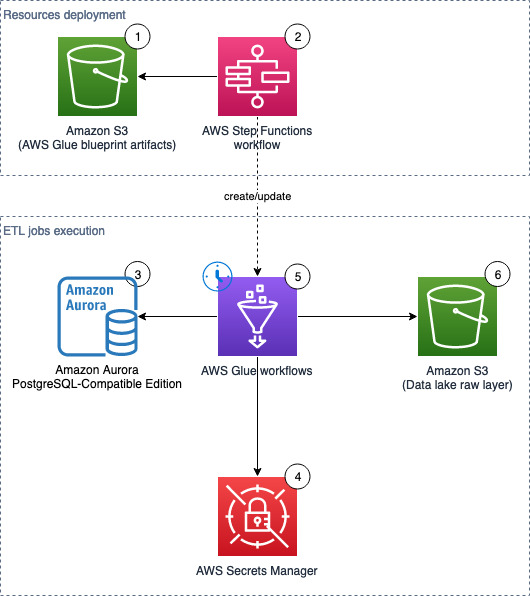
The solution workflow contains the following steps:
To follow along with this post, complete the following prerequisite steps.

In this step, we provision our solution resources with AWS CloudFormation.
This CloudFormation stack works only in AWS Regions where Amazon Aurora Serverless v1 is supported. Complete the following steps to create a database with sample data:

demo-database.default).ETLSubnet.ETLAZ.To find the subnet and corresponding Availability Zone, go to the Amazon Virtual Private Cloud (Amazon VPC) console and look at the columns Subnet ID and Availability Zone.
SecretsARN.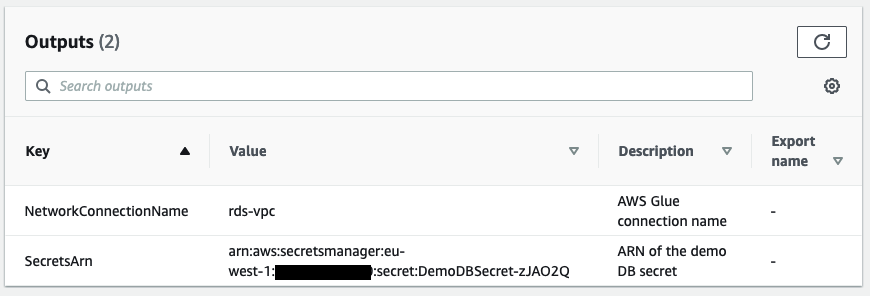
This CloudFormation stack creates the following resources:
DemoDBSecret) storing the connection details to the source databaserds_vpc) that can communicate with the source database and Amazon S3Now you can populate the database with sample data. The data is generated by referencing to the sample HR schema.
demo-<123456789012>.hr.This CloudFormation stack works in all AWS Regions.
data-lake-landing.data-lake-landing).data-lake-raw-layer).data-lake-raw-layer-123456789012-region) and Step Functions workflow (for example, data-lake-landing).
The CloudFormation stack creates the following resources:
The GlueExecutionRole is limited to the DemoDBSecret in Secrets Manager. If you need to connect to other databases which has a different endpoint/address or credentials, don’t forget to create new secrets and grant additional permissions to the IAM role or secrets so your AWS Glue jobs can authenticate with the source databases.
If you want to use this solution to perform ETL against your existing databases, follow this section. Otherwise, if you have deployed the CloudFormation stack for the database with sample data, jump to the section “Edit the workflow catalog”.
You need to have a running PostgreSQL database ready. To connect to other database engines, you need to customize this solution, particularly the jdbcUrl in the supplied PySpark script.
To create your Secrets Manager secret, complete the following steps:
aws/secretsmanager.rds-secrets).To create your AWS Glue connection, complete the following steps:
rds-vpc).You’re now ready to configure the rest of the solution.
To download the workflow catalog, complete the following steps:
GlueExecutionRole and DestinationBucketName. If you are using your own databases, you must change all vaules except WorkflowName, JobScheduleType, and ScheduleCronPattern.your_blueprint_name.json and upload it to your S3 bucket (for example, s3://data-lake-raw-layer-123456789012-eu-west-1/data-lake-landing.json).The example workflow has the JobScheduleType set to Cron. See Time-based schedules for jobs and crawlers for examples setting cron patterns. Alternatively set JobScheduleType to OnDemand.
See blueprint.cfg for the full list of parameters.
The provided workflow catalog JSON file contains job definitions of seven tables: public.regions, public.countries, public.locations, public.departments, public.jobs, public.employees, and public.job_history.
The sample script performs the following:
jdbc_df = (spark.read.format("jdbc")
           .option("url", jdbcUrl)
           .option("user", secret["username"])
           .option("password", secret["password"])
           .option("query", sql_query)
           .load()
)df_withdate = jdbc_df.withColumn("ingestion_timestamp", lit(current_timestamp()))Prepare your AWS Glue blueprint with the following steps:
blueprint.cfg, jdbc_to_s3.py, layout.py; exclude any folders) as your_blueprint_name.zip (for example, data-lake-landing.zip):s3://data-lake-raw-layer-123456789012-region/data-lake-landing.zip).Now you should have two files uploaded to your S3 bucket.

To run the Step Functions workflow, complete the following steps:
data-lake-landing) and choose View details.It’s normal to have some intermediate steps with the status “Caught error.”

When the workflow catalog contains a large number of ETL job entries, you can expect some delays. In our test environment, creating 100 jobs from a clean state can take around 22 minutes; the second run (deleting existing AWS Glue resources and creating 100 jobs) can take around 27 minutes.
To check the workflow, complete the following steps:
workflow_config.json are listed.s3://data-lake-raw-layer-123456789012-region/database/table/ingestion_date=yyyy-mm-dd/).
This section describes the major steps in the Step Functions workflow.
A blueprint allows you to parameterize a workflow (defining jobs and crawlers), and subsequently generate multiple AWS Glue workflows reusing the same code logic to handle similar data ETL activities. The following diagram illustrates the AWS Glue blueprint registration part of the Step Functions workflow.

The step Glue: CreateBlueprint takes the ZIP archive in Amazon S3 (sample) and registers it for later use.
To understand how to develop a blueprint, see Developing blueprints in AWS Glue.
The step S3: ParseGlueWorkflowsConfig triggers the following Map state, and runs a set of steps for each element of an input array.

We set the maximum concurrency to five parallel iterations to lower the chance of exceeding the maximum allowed API request rate (per account per Region). For each ETL job definition, the Step Functions workflow cleans up relevant AWS Glue resources (if they exist), including the workflow, job, and trigger.
For more information on the Map state, refer to Map.
Within the Map state, the step Glue: CreateWorkflowFromBlueprint starts an asynchronous process to create the AWS Glue workflow (for each job definition), and the jobs and triggers that the workflow encapsulates.

In this solution, all AWS Glue workflows share the same logic, beginning with a trigger to handle the schedule, followed by a job to run the ETL logic.
As indicated by the step CreateWorkflowFailed, any AWS Glue blueprint creation failure stops the whole Step Functions workflow and marks it with a failed status. Note that no rollback will happen. Fix the errors and rerun the Step Functions workflow. This will not result in duplicated AWS Glue resources and existing ones will be cleaned up in the process.
Note the following limitations of this solution:
To avoid incurring future charges, perform the following steps:
s3://data-lake-raw-layer-123456789012-eu-west-1/data-lake-landing.json) and replace the value of JobScheduleType to OnDemand for all workflow definitions.data-lake-landing)._starting_trigger have the trigger type On-demand instead of Schedule._starting_trigger.WorkflowName defined in the workflow catalog.WorkflowName defined in the workflow catalog.AWS Glue blueprints allow data engineers to build and maintain AWS Glue jobs landing data from RDBMS to your data lake at scale.By adopting this standardized and reusable approach, instead of maintaining hundreds of AWS Glue jobs, you now keep track the workflow catalog. When you have new tables to land to your data lake, simply add the entries to your workflow catalog and rerun the Step Functions workflow to deploy resources.
We highly encourage you to customize the blueprints for your multi-step data pipeline (for example, detect and mask sensitive data) and make them available to your organization and the AWS Glue community. To get started, see the Performing complex ETL activities using blueprints and workflows in AWS Glue and the sample blueprints on GitHub. If you have any questions, please leave a comment.
 Moustafa Mahmoud is a Solutions Architect of AWS Data Lab with a passion for data integration, data analysis, machine learning, and BI. Moustafa helps customers convert their ideas to a production-ready data product on AWS. He has over 10 years of experience as a data engineer, machine learning practitioner, and software developer. In his spare time, Moustafa loves exploring nature, reading, and spending time with friends and family.
 Corvus Lee is a Solutions Architect of AWS Data Lab. He enjoys all kinds of data-related discussions, and helps customers build MVPs using AWS Databases, Analytics, and Machine Learning services.
Post Syndicated from Greg Wiseman original https://blog.rapid7.com/2022/10/11/patch-tuesday-october-2022/
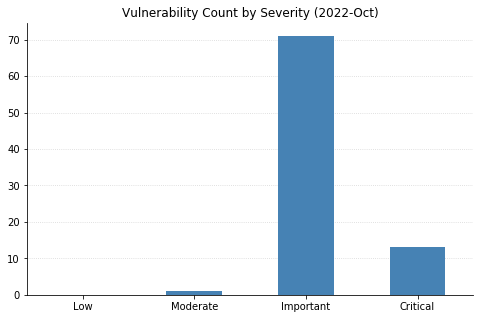
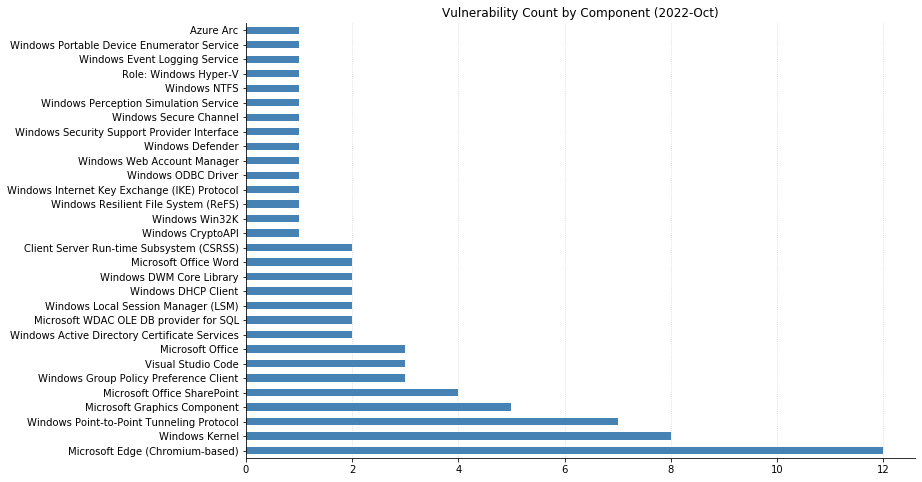
The October batch of CVEs published by Microsoft includes 96 vulnerabilities, including 12 fixed earlier this month that affect the Chromium project used by their Edge browser.
Top of mind for many this month is whether Microsoft would patch the two Exchange Server zero-day vulnerabilities (CVE-2022-41040 and CVE-2022-41082) disclosed at the end of September. While Microsoft was relatively quick to acknowledge the vulnerabilities and provide mitigation steps, their guidance has continually changed as the recommended rules to block attack traffic get bypassed. This whack-a-mole approach seems likely to continue until a proper patch addressing the root causes is available; unfortunately, it doesn’t look like that will be happening today. Thankfully, the impact should be more limited than 2021’s ProxyShell and ProxyLogon vulnerabilities due to attackers needing to be authenticated to the server for successful exploitation. Reports are also surfacing about an additional zero-day distinct from these being used in ransomware attacks; however, these have not yet been substantiated.
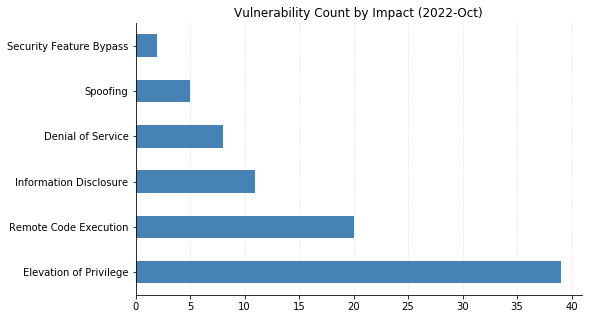
Microsoft did address two other zero-day vulnerabilities with today’s patches. CVE-2022-41033, an Elevation of Privilege vulnerability affecting the COM+ Event System Service in all supported versions of Windows, has been seen exploited in the wild. CVE-2022-41043 is an Information Disclosure vulnerability affecting Office for Mac that was publicly disclosed but not (yet) seen exploited in the wild.
Nine CVEs categorized as Remote Code Execution (RCE) with Critical severity were also patched today – seven of them affect the Point-to-Point Tunneling Protocol, and like those fixed last month, require an attacker to win a race condition to exploit them. CVE-2022-38048 affects all supported versions of Office, and CVE-2022-41038 could allow an attacker authenticated to SharePoint to execute arbitrary code on the server, provided the account has “Manage List” permissions.
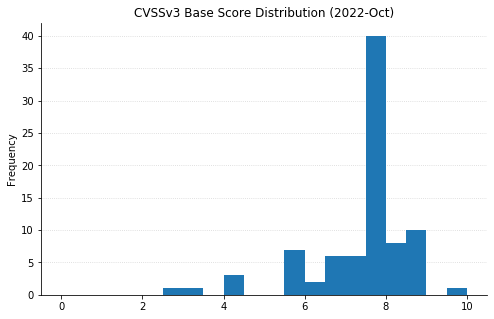
Maxing out the CVSS base score with a 10.0 this month is CVE-2022-37968, an Elevation of Privilege vulnerability in the Azure Arc-enabled Kubernetes cluster Connect component. It’s unclear why Microsoft has assigned such a high score, given that an attacker would need to know the randomly generated external DNS endpoint for an Azure Arc-enabled Kubernetes cluster (arguably making the Attack Complexity “High”). That said, if this condition is met then an unauthenticated user could become a cluster admin and potentially gain control over the Kubernetes cluster. Users of Azure Arc and Azure Stack Edge should check whether auto-updates are turned on, and if not, upgrade manually as soon as possible.
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-37968 | Azure Arc-enabled Kubernetes cluster Connect Elevation of Privilege Vulnerability | No | No | 10 | Yes |
| CVE-2022-38017 | StorSimple 8000 Series Elevation of Privilege Vulnerability | No | No | 6.8 | Yes |
| CVE-2022-35829 | Service Fabric Explorer Spoofing Vulnerability | No | No | 6.2 | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-41035 | Microsoft Edge (Chromium-based) Spoofing Vulnerability | No | No | 8.3 | Yes |
| CVE-2022-3373 | Chromium: CVE-2022-3373 Out of bounds write in V8 | No | No | N/A | Yes |
| CVE-2022-3370 | Chromium: CVE-2022-3370 Use after free in Custom Elements | No | No | N/A | Yes |
| CVE-2022-3317 | Chromium: CVE-2022-3317 Insufficient validation of untrusted input in Intents | No | No | N/A | Yes |
| CVE-2022-3316 | Chromium: CVE-2022-3316 Insufficient validation of untrusted input in Safe Browsing | No | No | N/A | Yes |
| CVE-2022-3315 | Chromium: CVE-2022-3315 Type confusion in Blink | No | No | N/A | Yes |
| CVE-2022-3313 | Chromium: CVE-2022-3313 Incorrect security UI in Full Screen | No | No | N/A | Yes |
| CVE-2022-3311 | Chromium: CVE-2022-3311 Use after free in Import | No | No | N/A | Yes |
| CVE-2022-3310 | Chromium: CVE-2022-3310 Insufficient policy enforcement in Custom Tabs | No | No | N/A | Yes |
| CVE-2022-3308 | Chromium: CVE-2022-3308 Insufficient policy enforcement in Developer Tools | No | No | N/A | Yes |
| CVE-2022-3307 | Chromium: CVE-2022-3307 Use after free in Media | No | No | N/A | Yes |
| CVE-2022-3304 | Chromium: CVE-2022-3304 Use after free in CSS | No | No | N/A | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-41034 | Visual Studio Code Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-41083 | Visual Studio Code Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-41032 | NuGet Client Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-41042 | Visual Studio Code Information Disclosure Vulnerability | No | No | 7.4 | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-41038 | Microsoft SharePoint Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-41036 | Microsoft SharePoint Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-41037 | Microsoft SharePoint Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-38053 | Microsoft SharePoint Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-41031 | Microsoft Word Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38048 | Microsoft Office Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38049 | Microsoft Office Graphics Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38001 | Microsoft Office Spoofing Vulnerability | No | No | 6.5 | Yes |
| CVE-2022-41043 | Microsoft Office Information Disclosure Vulnerability | No | Yes | 3.3 | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-37971 | Microsoft Windows Defender Elevation of Privilege Vulnerability | No | No | 7.1 | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-38016 | Windows Local Security Authority (LSA) Elevation of Privilege Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-38045 | Server Service Remote Protocol Elevation of Privilege Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-37984 | Windows WLAN Service Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38003 | Windows Resilient File System Elevation of Privilege | No | No | 7.8 | Yes |
| CVE-2022-38028 | Windows Print Spooler Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38039 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37995 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37979 | Windows Hyper-V Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37970 | Windows DWM Core Library Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37980 | Windows DHCP Client Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38050 | Win32k Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37983 | Microsoft DWM Core Library Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37998 | Windows Local Session Manager (LSM) Denial of Service Vulnerability | No | No | 7.7 | Yes |
| CVE-2022-37973 | Windows Local Session Manager (LSM) Denial of Service Vulnerability | No | No | 7.7 | Yes |
| CVE-2022-38036 | Internet Key Exchange (IKE) Protocol Denial of Service Vulnerability | No | No | 7.5 | No |
| CVE-2022-38027 | Windows Storage Elevation of Privilege Vulnerability | No | No | 7 | Yes |
| CVE-2022-38021 | Connected User Experiences and Telemetry Elevation of Privilege Vulnerability | No | No | 7 | Yes |
| CVE-2022-37974 | Windows Mixed Reality Developer Tools Information Disclosure Vulnerability | No | No | 6.5 | Yes |
| CVE-2022-38046 | Web Account Manager Information Disclosure Vulnerability | No | No | 6.2 | Yes |
| CVE-2022-37965 | Windows Point-to-Point Tunneling Protocol Denial of Service Vulnerability | No | No | 5.9 | Yes |
| CVE-2022-37996 | Windows Kernel Memory Information Disclosure Vulnerability | No | No | 5.5 | Yes |
| CVE-2022-38025 | Windows Distributed File System (DFS) Information Disclosure Vulnerability | No | No | 5.5 | Yes |
| CVE-2022-38030 | Windows USB Serial Driver Information Disclosure Vulnerability | No | No | 4.3 | Yes |
| CVE | Title | Exploited? | Publicly disclosed? | CVSSv3 base score | Has FAQ? |
|---|---|---|---|---|---|
| CVE-2022-37982 | Microsoft WDAC OLE DB provider for SQL Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-38031 | Microsoft WDAC OLE DB provider for SQL Server Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-38040 | Microsoft ODBC Driver Remote Code Execution Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-37976 | Active Directory Certificate Services Elevation of Privilege Vulnerability | No | No | 8.8 | Yes |
| CVE-2022-30198 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-22035 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-24504 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-33634 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-38047 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-38000 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-41081 | Windows Point-to-Point Tunneling Protocol Remote Code Execution Vulnerability | No | No | 8.1 | Yes |
| CVE-2022-37986 | Windows Win32k Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37988 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38037 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38038 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37990 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37991 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37999 | Windows Group Policy Preference Client Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37993 | Windows Group Policy Preference Client Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37994 | Windows Group Policy Preference Client Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37975 | Windows Group Policy Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-38051 | Windows Graphics Component Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37997 | Windows Graphics Component Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-33635 | Windows GDI+ Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37987 | Windows Client Server Run-time Subsystem (CSRSS) Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-37989 | Windows Client Server Run-time Subsystem (CSRSS) Elevation of Privilege Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-41033 | Windows COM+ Event System Service Elevation of Privilege Vulnerability | Yes | No | 7.8 | Yes |
| CVE-2022-38044 | Windows CD-ROM File System Driver Remote Code Execution Vulnerability | No | No | 7.8 | Yes |
| CVE-2022-33645 | Windows TCP/IP Driver Denial of Service Vulnerability | No | No | 7.5 | No |
| CVE-2022-38041 | Windows Secure Channel Denial of Service Vulnerability | No | No | 7.5 | No |
| CVE-2022-34689 | Windows CryptoAPI Spoofing Vulnerability | No | No | 7.5 | Yes |
| CVE-2022-37978 | Windows Active Directory Certificate Services Security Feature Bypass | No | No | 7.5 | Yes |
| CVE-2022-38042 | Active Directory Domain Services Elevation of Privilege Vulnerability | No | No | 7.1 | Yes |
| CVE-2022-38029 | Windows ALPC Elevation of Privilege Vulnerability | No | No | 7 | Yes |
| CVE-2022-38033 | Windows Server Remotely Accessible Registry Keys Information Disclosure Vulnerability | No | No | 6.5 | Yes |
| CVE-2022-35770 | Windows NTLM Spoofing Vulnerability | No | No | 6.5 | Yes |
| CVE-2022-37977 | Local Security Authority Subsystem Service (LSASS) Denial of Service Vulnerability | No | No | 6.5 | No |
| CVE-2022-38032 | Windows Portable Device Enumerator Service Security Feature Bypass Vulnerability | No | No | 5.9 | Yes |
| CVE-2022-38043 | Windows Security Support Provider Interface Information Disclosure Vulnerability | No | No | 5.5 | Yes |
| CVE-2022-37985 | Windows Graphics Component Information Disclosure Vulnerability | No | No | 5.5 | Yes |
| CVE-2022-38026 | Windows DHCP Client Information Disclosure Vulnerability | No | No | 5.5 | Yes |
| CVE-2022-38034 | Windows Workstation Service Elevation of Privilege Vulnerability | No | No | 4.3 | Yes |
| CVE-2022-37981 | Windows Event Logging Service Denial of Service Vulnerability | No | No | 4.3 | Yes |
| CVE-2022-38022 | Windows Kernel Elevation of Privilege Vulnerability | No | No | 2.5 | Yes |
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=7prn-VO_2M8
Post Syndicated from original https://lwn.net/Articles/910848/
The Opus codec is an audio codec that
was designed from the beginning to avoid existing patents in the field and
be royalty-free for all users. It was standardized by the IETF in 2012 as
RFC 6716.
Now a company called Vectis (“a premier
“) is collecting
full-suite IP licensing and consultancy boutique
patents that are claimed to read on Opus as a way of demanding
royalties on its use.
“The planned Opus program will focus on hardware devices and will not be
“. (Thanks to Paul Wise).
directed towards open-source software, applications, services, or
content
Post Syndicated from Jeremy Milk original https://www.backblaze.com/blog/media-workflowing-in-the-big-apple-nab-show-new-york-preview/
You can send media in milliseconds to just about every corner of the earth with an origin store at your favorite cloud storage company and a snappy CDN. Sadly, delivering people across continents is a touch more complicated and time intensive. Nevertheless, the Backblaze team is saddling up planes, trains, and automobiles to bring the latest on media workflows to the attendees of NAB Show New York. Whether you’re there in person or virtually, we’ll be discussing and demo-ing all the newest Backblaze B2 Cloud Storage solutions that will ensure your data can travel with ease—no mass transit needed—everywhere you need it to be.
If you’re attending the NAB Show New York, join us in booth 1239 to learn about integrating B2 Cloud Storage into your workflow. Stop by anytime or you can schedule a meeting here. We’d love to see you.
Our booth will have all the goodness you’d expect of us: partners, friendly faces, spots to take a load off and talk about making your data work harder, and, of course, some next-level SWAG. Let’s get into what you can expect.
Our team is on hand to talk you through two new offerings that have been generating a lot of excitement among teams across media organizations:
We’ve gathered materials and expertise to discuss or demo our six most asked about workflow improvements. We’re happy to talk about many other tools and improvements, but here are the six areas we expect to talk about the most:
“The more we get together, the happier we’ll be,” might as well be the theme lyric of cloud workflows. Combining best of breed platforms unlocks better value and functionality, and offers you the ability to build your cloud stack exactly how you need it for your business. We’ve got a large ecosystem of Alliance Partners, and we’re happy to get deep into your needs and demo how you can combine Backblaze B2 Cloud Storage with one or more partners including iconik, LucidLink, Synology (who will also be right next to us in the Javits Center!), and Fastly to best achieve your objectives.
Whether it’s in person at NAB Show New York or virtually when it works for you, we’d love to walk you through any of the solutions we can serve for hardworking media teams. If you will be in Manhattan, schedule a meeting to ensure you’ll get the right expert on our team, then stick around for the swag and good times. This invitation applies to you too, Channel Partners and Resellers—whether you have active projects or just want to learn more, let’s meet up and chat about ways to deliver more value together. If you’re not making the trip, not a problem. Just contact us here so we can arrange to help virtually.
The post Media Workflowing in The Big Apple: NAB Show New York Preview appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=rSamKRC0Tuw
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=q4IEFWH8XHA
Post Syndicated from original https://lwn.net/Articles/910833/
Version 7.0.0
of the VirtualBox virtualization system is out. Changes include support
for fully encrypted virtual machines, a new performance-monitoring tool,
improved theme support, and a number of new devices.
Post Syndicated from original https://lwn.net/Articles/910828/
Security updates have been issued by Debian (connman, dbus, git, isc-dhcp, strongswan, and wordpress), Fedora (rubygem-pdfkit and seamonkey), Red Hat (gnutls, nettle, rh-ruby27-ruby, and rh-ruby30-ruby), SUSE (libgsasl, python, and snakeyaml), and Ubuntu (graphite2, linux, linux-aws, linux-aws-5.15, linux-azure, linux-azure-5.15,
linux-gcp, linux-gke, linux-gkeop, linux-hwe-5.15, linux-kvm,
linux-lowlatency, linux-lowlatency-hwe-5.15, linux-oracle, linux-raspi, linux, linux-aws, linux-bluefield, linux-gke, linux-gkeop, linux-hwe-5.4,
linux-ibm, linux-ibm-5.4, linux-kvm, linux-oracle, linux, linux-dell300x, linux-kvm, linux-oracle, linux-raspi2,
linux-snapdragon, linux-hwe, linux-oracle, openssh, and pcre3).
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/10/inserting-a-backdoor-into-a-machine-learning-system.html
Interesting research: “ImpNet: Imperceptible and blackbox-undetectable backdoors in compiled neural networks, by Tim Clifford, Ilia Shumailov, Yiren Zhao, Ross Anderson, and Robert Mullins:
Abstract: Early backdoor attacks against machine learning set off an arms race in attack and defence development. Defences have since appeared demonstrating some ability to detect backdoors in models or even remove them. These defences work by inspecting the training data, the model, or the integrity of the training procedure. In this work, we show that backdoors can be added during compilation, circumventing any safeguards in the data preparation and model training stages. As an illustration, the attacker can insert weight-based backdoors during the hardware compilation step that will not be detected by any training or data-preparation process. Next, we demonstrate that some backdoors, such as ImpNet, can only be reliably detected at the stage where they are inserted and removing them anywhere else presents a significant challenge. We conclude that machine-learning model security requires assurance of provenance along the entire technical pipeline, including the data, model architecture, compiler, and hardware specification.
Ross Anderson explains the significance:
The trick is for the compiler to recognise what sort of model it’s compiling—whether it’s processing images or text, for example—and then devising trigger mechanisms for such models that are sufficiently covert and general. The takeaway message is that for a machine-learning model to be trustworthy, you need to assure the provenance of the whole chain: the model itself, the software tools used to compile it, the training data, the order in which the data are batched and presented—in short, everything.