Version
0.11 of the Tuba
fediverse client has been released. Notable changes in this release include
support for Mastodon collections
and quotes,
ability to create custom thumbnails for attachments, a new emoji picker, a build
for Android, as well as many other enhancements.
At the outset of his PyCon US 2026
talk, Trey Hunner said that his goal was for attendees to stop representing
filesystem paths as strings and to use pathlib
instead. That’s kind of a tall order, at least for longtime Python users,
since string-based paths have been pervasive—and mostly work. It is that
“mostly” part that makes Hunner want to see things change, of course, so he
set out to describe a lesser-known corner of the language and to try to
change some minds.
Cerebras this week has introduced a major upgrade to its hardware ecosystem. The company is launching their first rack-scale AI inference system, the CS-4, which is powered by the upgraded WSE-3 Turbo processor
Clario, part of Thermo Fisher Scientific, uses Amazon Bedrock to automate PHI (Protected Health Information) and PII (Personally Identifiable Information) detection across thousands of DICOM (Digital Imaging and Communications in Medicine) image slices in clinical trials. Each image slice may carry PII or PHI hidden in metadata tags, in custom vendor fields, or burned directly into the pixels. Across imaging sites, central labs, sponsors, and CROs (Contract Research Organizations), every one of those slices must be cleared of PII and PHI before the image moves downstream.
DICOM is the universal standard for storing, transmitting, and managing medical imaging data across healthcare systems. In clinical trials, DICOM images play a critical role by providing objective, quantifiable evidence of a patient’s medical condition throughout the study lifecycle. From baseline imaging to follow-up scans, modalities such as MRI, CT, PET, and X-ray generate DICOM files. Radiologists, clinicians, and sponsors use these files to assess treatment efficacy, monitor disease progression, and support regulatory submissions. These images serve as a core component of the clinical evidence package, making their accurate management and standardized handling essential to trial integrity.
In this post, we share how the Clario team designed an automated PHI and PII detection solution on AWS for DICOM imaging data, the key design decisions behind the architecture, and the lessons the team learned along the way.
About Clario, part of Thermo Fisher Scientific
Clario science and endpoint solutions support the clinical trials industry through the systematic collection, management, and analysis of specific, predefined outcomes (endpoints) to evaluate a treatment’s safety and effectiveness. For more than 50 years, Clario endpoint solutions have been deployed more than 30,000 times, and since 2015, they have supported more than 700 FDA and EMA new drug approvals.
Business challenge
Clearing PII and PHI from every image slice in the clinical trial is only part of the problem. The imaging workflow around this clearing process must be just as rigorous. A well-structured imaging workflow supports every DICOM file captured across globally distributed trial sites. Files are ingested automatically, consistently standardized, and rigorously validated at every step of the journey. Enforcing standardized image acquisition protocols across sites and geographies alleviates inconsistencies. These inconsistencies could otherwise impact data quality or delay regulatory submissions. A centralized imaging infrastructure that maintains complete metadata traceability, including acquisition parameters, imaging equipment details, and timestamps, supports a fully auditable workflow aligned with GCP (Good Clinical Practice) requirements. This empowers sponsors and CROs to move faster with greater confidence and significantly reduces the risk of data queries or compliance gaps.
An equally important aspect of managing DICOM imaging data in clinical trials is embedding intelligent, automated PHI and PII protection directly into the data management process. DICOM files carry more than images. They include metadata and tags, which can contain sensitive information such as patient names, dates of birth, medical record numbers, and facility identifiers. This sensitive information must be carefully managed before sponsors, CROs, or third-party stakeholders receive the data. Proactively verifying that PII and PHI are accurately identified and de-identified at the source is a critical best practice that safeguards patient privacy in compliance with HIPAA, GDPR, and ICH E6 guidelines. Automated de-identification tools that adhere to DICOM Supplement 142 and NEMA (National Electrical Manufacturers Association) standards reinforce data security and regulatory trust. They also preserve the full clinical and scientific value of imaging data, so trial teams can support confident, high-quality regulatory submissions.
To address these challenges, the Clario team built a comprehensive PHI/PII detection solution on AWS using Amazon Bedrock (Anthropic’s Claude Sonnet 4.5 on Amazon Bedrock) that combines automation, accuracy, and security throughout the clinical trial imaging workflow.
Why Amazon Bedrock and Amazon Textract
When evaluating options for building the solution, the Clario team chose to standardize on Amazon Bedrock and Amazon Textract for several key reasons:
Scalability without re-architecting: Amazon Bedrock and Amazon Textract provide scalability, reliability, and strong performance. The solution architecture can scale from a handful of documents to millions without re-architecting the solution or managing additional infrastructure. AWS manages the underlying capacity, so you can focus on building features instead of tuning servers or models.
Security and compliance: Keeping customer data secure is non-negotiable. By using Amazon Bedrock and Amazon Textract within Clario managed AWS accounts, processing remains inside a hardened AWS environment, taking advantage of AWS Identity and Access Management (IAM), Amazon Virtual Private Cloud controls, and encryption at rest and in transit. The Clario team can align closely with its organization’s security, compliance, and data residency requirements.
Managed foundation models: With Amazon Bedrock, the Clario team can access a range of high-quality foundation models as a fully managed service, without having to manage model training, hosting, or updates. This shortens the time to market, and you can iterate quickly as new models and capabilities become available in Amazon Bedrock.
Purpose-built OCR and document processing: Amazon Textract provides purpose‑built optical character recognition (OCR) and intelligent document processing, which significantly improves accuracy over traditional OCR engines. Its ability to automatically detect and extract text, tables, and key‑value pairs from complex documents and images reduces the amount of custom parsing logic that must be maintained.
End-to-end observability: Running on AWS provides end-to-end observability across the logs, metrics, and traces through services like Amazon CloudWatch and AWS CloudTrail. The Clario team can enforce governance policies, audit permissions, and track model and document processing usage centrally.
Extensible AI foundation: Because the solution builds on Amazon Bedrock and Amazon Textract, the Clario team can adopt new models and document processing features as they become available, without re-architecting.
Solution overview
The solution is built entirely on AWS, designed to bring greater efficiency, accuracy, and security to the detection of PHI and PII embedded within DICOM files. Accessible through Amazon API Gateway with TLS encryption in transit, IAM-backed authorization, and rate limiting, the detection workflow is readily consumable by multiple downstream systems with minimal integration effort.
Clinical trial sites store their DICOM images in Amazon Simple Storage Service (Amazon S3). The detection workflow retrieves each file from that bucket and processes it through the detection pipeline, so every ingestion step is logged and auditable for clinical trial security and compliance reviews. The workflow scans both standard and custom private DICOM metadata tags for PHI and PII. This covers the vendor-specific and non-standard tags where sensitive information often hides. Supporting both DICOM (.dcm) and PDF file formats, the solution is well-positioned to address PHI detection needs across the most used file types in clinical trial workflows.
The Clario AI team made a few deliberate design decisions early on. They ran the backend on Amazon Elastic Kubernetes Service (Amazon EKS) because a single DICOM series can span thousands of slices, and the detection workload is long-running and memory-intensive. They chose Amazon Relational Database Service (Amazon RDS) for PostgreSQL to persist processing metadata because the audit trail needs relational queries and strong consistency for compliance reporting. And they put the service behind Amazon API Gateway so that authentication, API-key management, and rate limiting are handled at the edge, keeping the backend focused on detection.
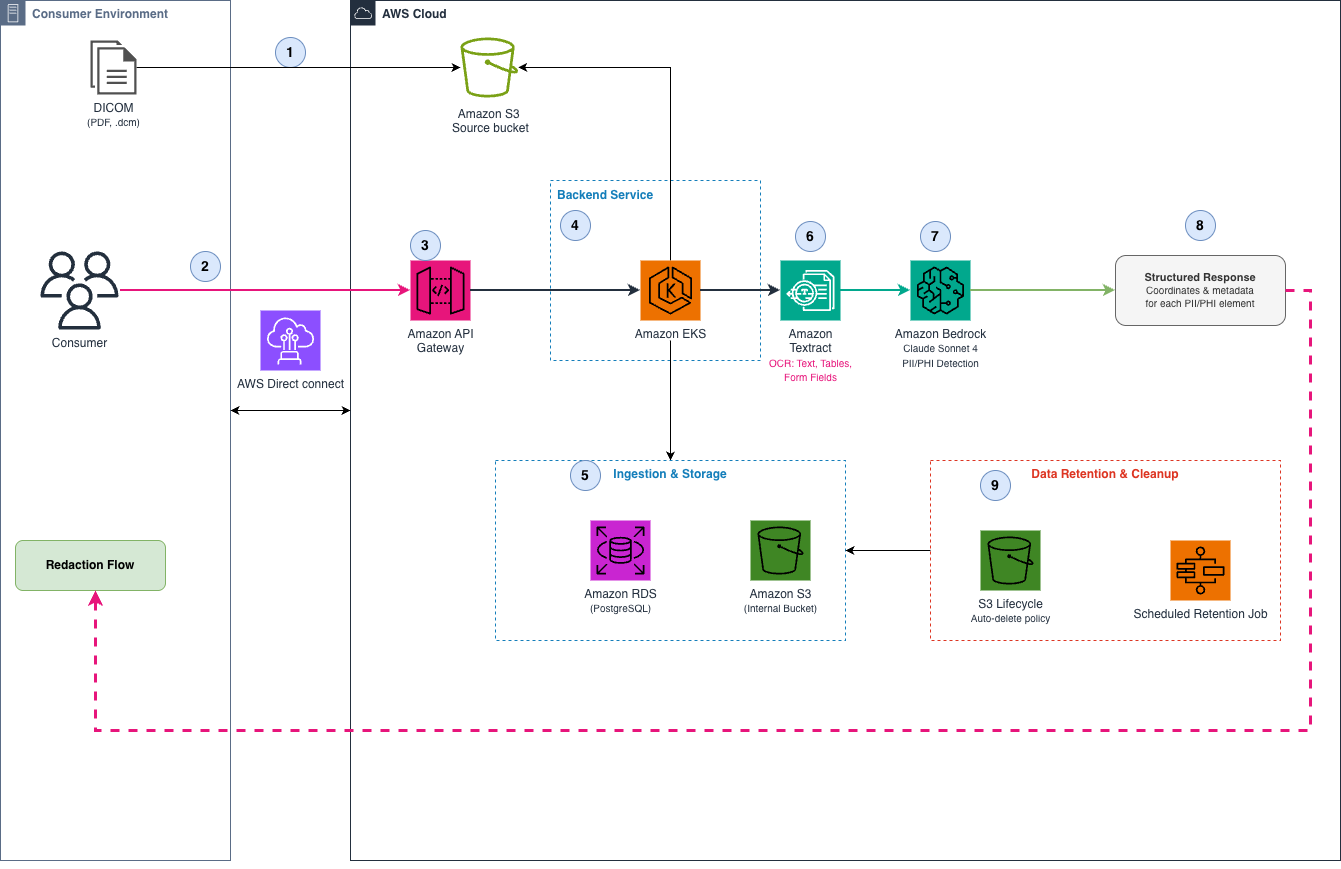
The following diagram and steps show how a DICOM document moves from upload through detection to structured output:
Figure 1: Solution architecture for DICOM image ingestion, detection pipeline, and data retention workflow
The following steps describe the data flow through the solution, as shown in the architecture diagram:
A consumer, such as an upstream imaging application, first uploads the DICOM image document to an Amazon S3 bucket location that is accessible to the solution.
The consumer then calls the Clario Internal API running on Amazon API Gateway, providing their consumer-specific API key and the location of the document. This call initiates the DICOM image analysis workflow.
Amazon API Gateway fronts the API and receives the incoming request. API Gateway validates the API key and, on success, forwards the request to the detection backend endpoint running on Amazon EKS to initiate processing.
The solution performs initial checks on the file location (for example, URL format, access, and basic metadata) and then begins the PII/PHI identification process. The pipeline retrieves the file from the source S3 bucket and ingests it into the detection workflow.
The file is stored in an internal Amazon S3 bucket and relevant metadata persisted in a PostgreSQL database on Amazon RDS to support downstream processing and auditability.
The workflow invokes Amazon Textract to perform OCR and intelligent document parsing. Textract extracts text, tables, and form fields from the uploaded document, returning a structured representation of the content.
The OCR output is then passed to a large language model (Anthropic’s Claude Sonnet 4.5 on Amazon Bedrock) that is configured to analyze the extracted text and identify potential PII/PHI elements. The model evaluates the content and associates each detected sensitive element with its position in the document.
Once analysis is complete, the detection workflow returns a structured response to the consumer, containing the coordinates and related metadata for each piece of sensitive data identified in the document. The consumer can take follow‑up actions, such as redaction or masking.
To minimize data exposure and support compliance requirements, the ingested files and associated records are retained only for a limited window. The document stored in Amazon S3 is automatically deleted based on an Amazon S3 lifecycle retention policy, and corresponding records in Amazon RDS are removed via a scheduled cleanup job.
Deep image analysis and detection workflow
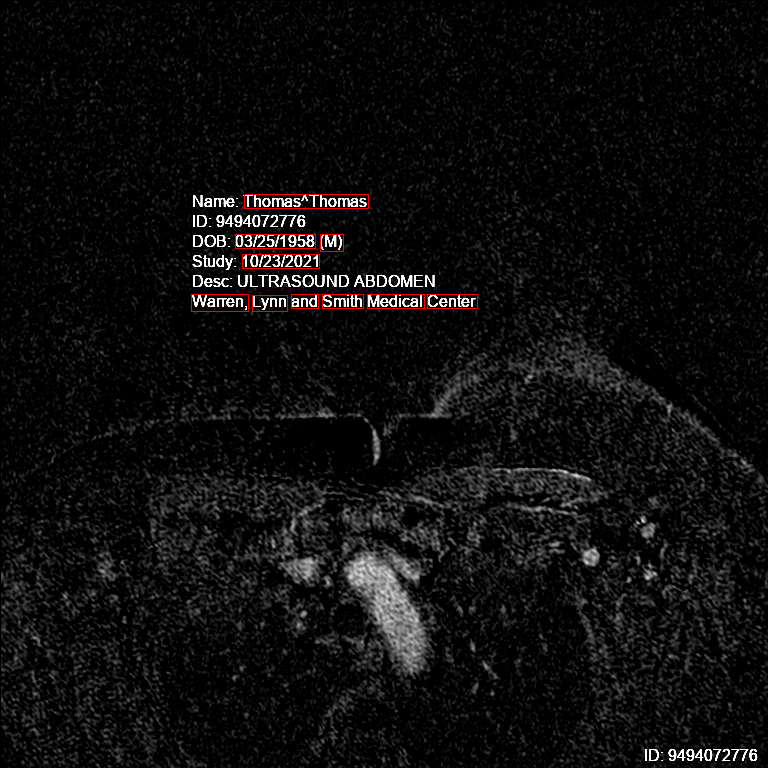
Beyond metadata, the solution uses Anthropic’s Claude Sonnet 4.5 on Amazon Bedrock to perform a deep scan of the actual image pixel content, detecting PHI or PII that may be physically burned into the image itself. This includes patient names, dates of birth, and patient IDs across every individual slice within a DICOM series that can span thousands of images.
When PHI or PII is identified, the solution precisely captures the spatial coordinates and type of sensitive information detected, passing these bounding box details downstream to integrated systems responsible for the actual pixel-level redaction. Separating detection from masking was a deliberate design decision. It preserves flexibility, supports full auditability, and a human-in-the-loop can review the flagged findings before redaction is applied.
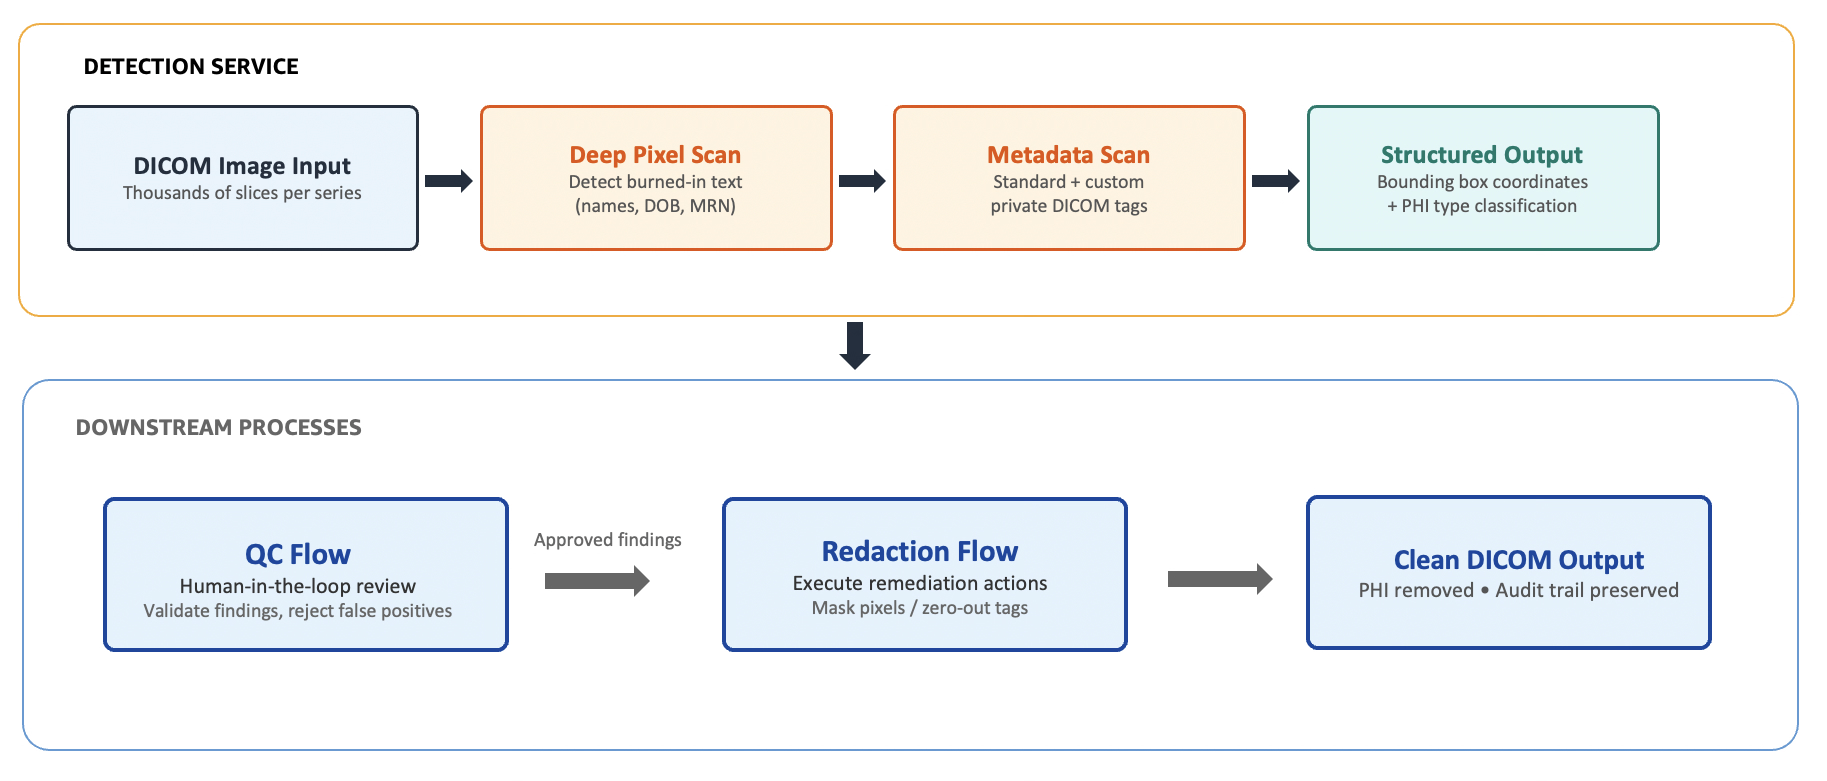
Figure 2: Deep image analysis and detection workflow showing the separation between AI-powered detection and human-supervised redaction
The detection solution returns structured coordinates for the identified PHI and PII, spanning burnt-in pixel text, standard DICOM header fields, and non-standard custom tags. The solution then hands these results off to two downstream processes. In the quality control (QC) flow, qualified reviewers validate the flagged findings and confirm which items require remediation. In the redaction flow, the system executes the appropriate action for each type of PHI identified: masking or overwriting burnt-in text within the image pixel data, or stripping and zeroing out sensitive DICOM metadata tags.
This separation of detection and redaction is intentional. The AI-powered detection solution focuses on comprehensive, high-recall identification across thousands of image slices and metadata fields. The redaction flow retains human oversight over the irreversible act of modifying clinical data, confirming that no PHI is left exposed and no clinically relevant information is removed.
Figure 3: Sample DICOM image with detection
With the detection pipeline in place, the next step was to measure how accurately it identifies PHI and PII across real-world clinical documents.
Evaluation methodology
The team validated the solution in three stages: building a representative test dataset, creating ground truth annotations, and running an automated evaluation pipeline.
Building a representative test dataset
The Clario generative AI team partnered with internal stakeholders to assemble a diverse dataset, including:
DICOM images with burned‑in annotations, overlays, and metadata.
PDF documents such as reports and clinical summaries.
The dataset intentionally included documents that do and do not contain sensitive PII/PHI, allowing the team to measure both the model’s ability to detect sensitive information and its ability to avoid false alarms.
Creating ground truth annotations
For each document in the dataset, ground truth labels were generated that capture:
The exact text corresponding to each PII/PHI element.
The bounding box coordinates for each element on the page where available.
These annotations form the “gold standard” that the Clario team can use to compare the output from the production pipeline.
Automated evaluation pipeline
The Clario team implemented a set of evaluation scripts that:
Run the full solution on each test DICOM or PDF, using the same workflow that powers the production system.
Collect the model predictions, including the detected PII/PHI text, associated labels (for example, name, date of birth, medical record number), and coordinates where available.
Compare predictions against ground truth using the following matching strategy:
For PDFs and DICOM images where coordinates are available, a match is performed by spatial proximity, treating a predicted bounding box as a correct match if it falls within a configurable tolerance (by default, 3 pixels for each element of the bounding box).
For DICOM metadata where coordinates are not available, a match is performed by a structured path.
Furthermore, the solution includes automated accuracy and performance (run time) checks, to improve system reliability across deployments. After validating the solution’s accuracy, the team assessed how it improves detection coverage across Clario clinical trial imaging workflows.
Results and benefits
The automated evaluation pipeline measured the solution’s detection performance against the manually annotated ground truth dataset across all three detection surfaces:
Detection surface
Detection F1
Label accuracy
PDF text
0.9775
98.12%
DICOM burned-in image text
0.9750
96.15%
DICOM metadata tags
0.9951
99.60%
Detection F1 measures how accurately the solution identifies PHI/PII instances. Label accuracy measures how correctly it classifies the type of identified PHI/PII (for example, person_name, date_of_birth, or gender).
These results demonstrate consistently high detection performance across all three data surfaces, with metadata tag detection achieving near-perfect accuracy. The solution meets the Clario generative AI team’s production-readiness bar for deployment in clinical trial workflows where compliance accuracy is non-negotiable.
Complete detection coverage
Manual QC reviewers bring deep domain expertise to PHI identification. But modern clinical trials generate an enormous volume of data: thousands of image slices per series, each with dozens of metadata tags, including non-standard vendor-specific fields. This volume makes exhaustive manual review impractical at scale. The automated solution extends that human expertise across the full dataset.
In internal testing conducted by the Clario team, the solution scanned 100% of image slices, standard DICOM header fields, and custom private tags in the test dataset. This comprehensive coverage complements the existing QC process by surfacing PHI occurrences that might otherwise require additional review passes, particularly in non-standard private tags and burned-in pixel text where sensitive data is less predictable.
Risk and compliance impact
By automating PII and PHI detection across metadata tags and image slices, the solution can strengthen an organization’s compliance posture against HIPAA, GDPR, and ICH E6 requirements.
Beyond the measurable results, the project surfaced several insights that can guide other organizations building similar solutions.
The AWS collaboration
The AWS Solutions Architecture team partnered with the Clario AI team throughout the design and optimization of the detection solution. Key areas of collaboration included:
Scaling and throughput optimization: Provided prescriptive guidance on Amazon EKS pod scaling strategy to handle DICOM series with thousands of slices per request without timeout or memory pressure and tuned concurrent invocations to Amazon Bedrock to maximize throughput within account-level quotas.
Cost-efficient inference architecture: Recommended batching strategies for Amazon Textract API calls and optimized prompt token usage for Claude Sonnet on Amazon Bedrock to reduce per-document inference cost at scale.
Data retention and security controls: Recommended auto-deletion workflow using Amazon S3 Lifecycle policies and Amazon RDS scheduled jobs to meet HIPAA and GDPR data minimization requirements.
Lessons learned and best practices
Throughout the development and deployment of this solution, several valuable insights emerged that can benefit other organizations implementing similar AI-powered PHI detection systems for clinical trial imaging data.
Evaluate models against production-representative data
The Clario AI team adopted a rigorous model evaluation process early in development. Many open-source frameworks and off-the-shelf detection models demonstrated acceptable performance on curated test samples but experienced significant accuracy degradation when exposed to the full variability of production data. This variability includes diverse imaging modalities, vendor-specific private tags, and inconsistent burned-in text formatting across globally distributed trial sites. This reinforced the importance of evaluating any AI model at realistic, production-level data volumes before adoption. The solution that proved most effective was a carefully tuned pipeline where Amazon Textract handles text extraction and Claude Sonnet on Amazon Bedrock performs PHI/PII classification, with prompt engineering optimized for the specific patterns found in clinical trial DICOM data.
Ground truth data is non-negotiable
Building a reliable, automated evaluation pipeline required the manual creation of a ground truth dataset. The team acknowledges this process is time-consuming but necessary. This highlighted a best practice that is frequently underestimated: investing in high-quality, manually validated ground truth data is a prerequisite for developing and maintaining a trustworthy automated detection system. Attempting to shortcut this step risks deploying a solution whose real-world accuracy remains unknown, an unacceptable risk in the context of clinical trial compliance.
Separating detection from masking improves flexibility and auditability
The Clario team deliberately separated the PHI/PII detection function from the actual pixel-level redaction. Rather than performing masking directly, the solution identifies the precise coordinates and type of PHI/PII detected, passing this structured output downstream to integrated systems responsible for redaction. This separation proved to be a sound best practice. It preserves workflow flexibility, a human expert can review the findings before anyone makes irreversible changes to the image data, and keeps human accountability and auditability clear at every step.
Human-in-the-loop review remains an essential safeguard
Automation accelerates the detection and flagging process, but a key lesson learned is that human oversight should remain an integral part of the workflow. Incorporating a human review step for flagged findings before masking makes sure that edge cases and model uncertainties are appropriately handled. In the context of clinical trial data, where accuracy and regulatory accountability are paramount, this human-in-the-loop approach provides an essential layer of quality assurance that purely automated systems alone cannot fully replace.
Conclusion
The Clario automated PHI/PII detection solution demonstrates how AWS services can transform clinical trial imaging workflows by combining speed, accuracy, and compliance. By replacing manual spot-checks with automated scanning of every slice and metadata tag, the solution delivers complete PHI/PII detection coverage, reducing the risk of missed detections while strengthening compliance with HIPAA, GDPR, and ICH E6 requirements.
The key architectural decisions, comprehensive coverage of custom private tags, separation of detection from redaction, and human-in-the-loop validation provide a blueprint for other organizations managing sensitive imaging data in regulated environments. These lessons learned highlight that successful automation in clinical trials requires not just advanced technology, but thoughtful design that balances efficiency with the rigorous quality standards that patient safety and regulatory compliance demand.
Next steps
Organizations looking to implement similar PHI/PII detection capabilities for clinical trial imaging can start by:
Evaluate current manual review processes: Map where reviewers spend the most time and where missed PHI poses the greatest compliance risk.
Assess custom private DICOM tags: Catalog vendor-specific and site-specific tags across your imaging network to define the full detection scope.
Build ground truth datasets: Annotate a representative sample with precise PHI labels to benchmark automated detection accuracy.
Design human-in-the-loop workflows: Define review checkpoints where qualified personnel validate flagged findings before redaction.
If you’re running a Mac fleet, Jamf is often where everything starts. It handles provisioning, policies, app installs——the orchestration that keeps your fleet sane. But backup is the thing that doesn’t fit. Jamf gives you control over every Mac, but it doesn’t protect the data on them. Backblaze closes that gap without changing how your team works.
Webinar: Building a Complete Mac Protection Strategy
Join Solution Engineers from Jamf and Backblaze for a practical discussion on building a complete Mac protection strategy.
The device ownership problem
Either you know who owns every device upfront (rare), or you don’t (common). Most teams end up doing some mix: devices that came pre-assigned, devices still waiting for user mapping, devices that migrated between teams. You write a script to fix it, then another to catch the next variation. Three months later, you’re not sure if every device is actually backed up or just supposed to be.
The new solution: Two ways to match devices to users. Pick the one that matches your reality.
This update solves the core friction: you don’t have to choose one deployment model anymore.
Method 1: Fixed email (for controlled environments) If you already know who owns each device at install time, for example, if you have clean HR data synced to Jamf, you can pass the user email directly during deployment. The installer uses it to set up the account automatically. No guessing, no drift.
Method 2: Dynamic user detection (for real-world environments) If you don’t have clean data upfront (e.g. when new devices arrive, get imaged, and wait for assignment) the installer waits until a user logs in. Once a user signs in, Backblaze can automatically associate the device with the appropriate user account based on the deployment configuration and identity information available on the device. This reduces the need for manual user assignment and helps prevent devices from being left unprotected.
Or mix them: some devices get email, others get dynamic detection. The system can now handle both in the same deployment.
What this means for your workflow
You push the Backblaze installer through a Jamf policy, same as any other app. Set your preferred method (fixed or dynamic) once at the group level, then let it run. Devices show up in the Backblaze console under the right user, with the right backup scope, no extra steps.
When something does need adjustment—a device moved teams, a user credential changed—you handle it the same way you’d handle any other Jamf-managed app. Script it, reconfigure it, whatever your existing process is. Backup can now follow the same deployment and management workflows your team already uses for other Jamf-managed applications.
Fewer things that can go wrong means less time managing edge cases
The friction point used to be this: you’d deploy backup, then spend the next week chasing down why a handful of devices aren’t appearing correctly. Someone’s account didn’t match. A device landed in the wrong group. Now you’re writing workarounds.
With two deployment methods that actually handle different scenarios instead of forcing everything into one model. The new deployment options reduce common onboarding issues that often require follow-up troubleshooting.Fewer edge cases means fewer scripts to maintain, fewer devices to manually fix, fewer things to check on at 3am.
It still runs the same way once it’s installed
Nothing else about Backblaze changes. It backs up user data automatically, without caps or limits. Pricing stays flat per device. Restore works the same way. This update is purely about getting it deployed cleanly—the actual backup part just keeps working.
How to start
Pick a small group of devices. Deploy through Jamf. Watch what happens for a week. You’ll see pretty quickly whether the user-matching is working and whether this fits your environment.
AI agents built on Amazon Bedrock AgentCore let clinical trial teams make fast, accurate enrollment decisions while keeping clinicians in control through human-in-the-loop oversight. According to the Tufts Center for the Study of Drug Development, 80 percent of clinical trials miss their enrollment timelines, and each day of delay costs an estimated $500,000.
Today, eligibility decisions rely on manual chart review across fragmented sources — EHR notes, lab results, imaging reports, and medication histories. Study teams spend hours reconstructing each candidate’s history and mapping it to protocol criteria. As protocols grow more complex, this doesn’t scale: screen failure rates stay high and enrollment targets slip.
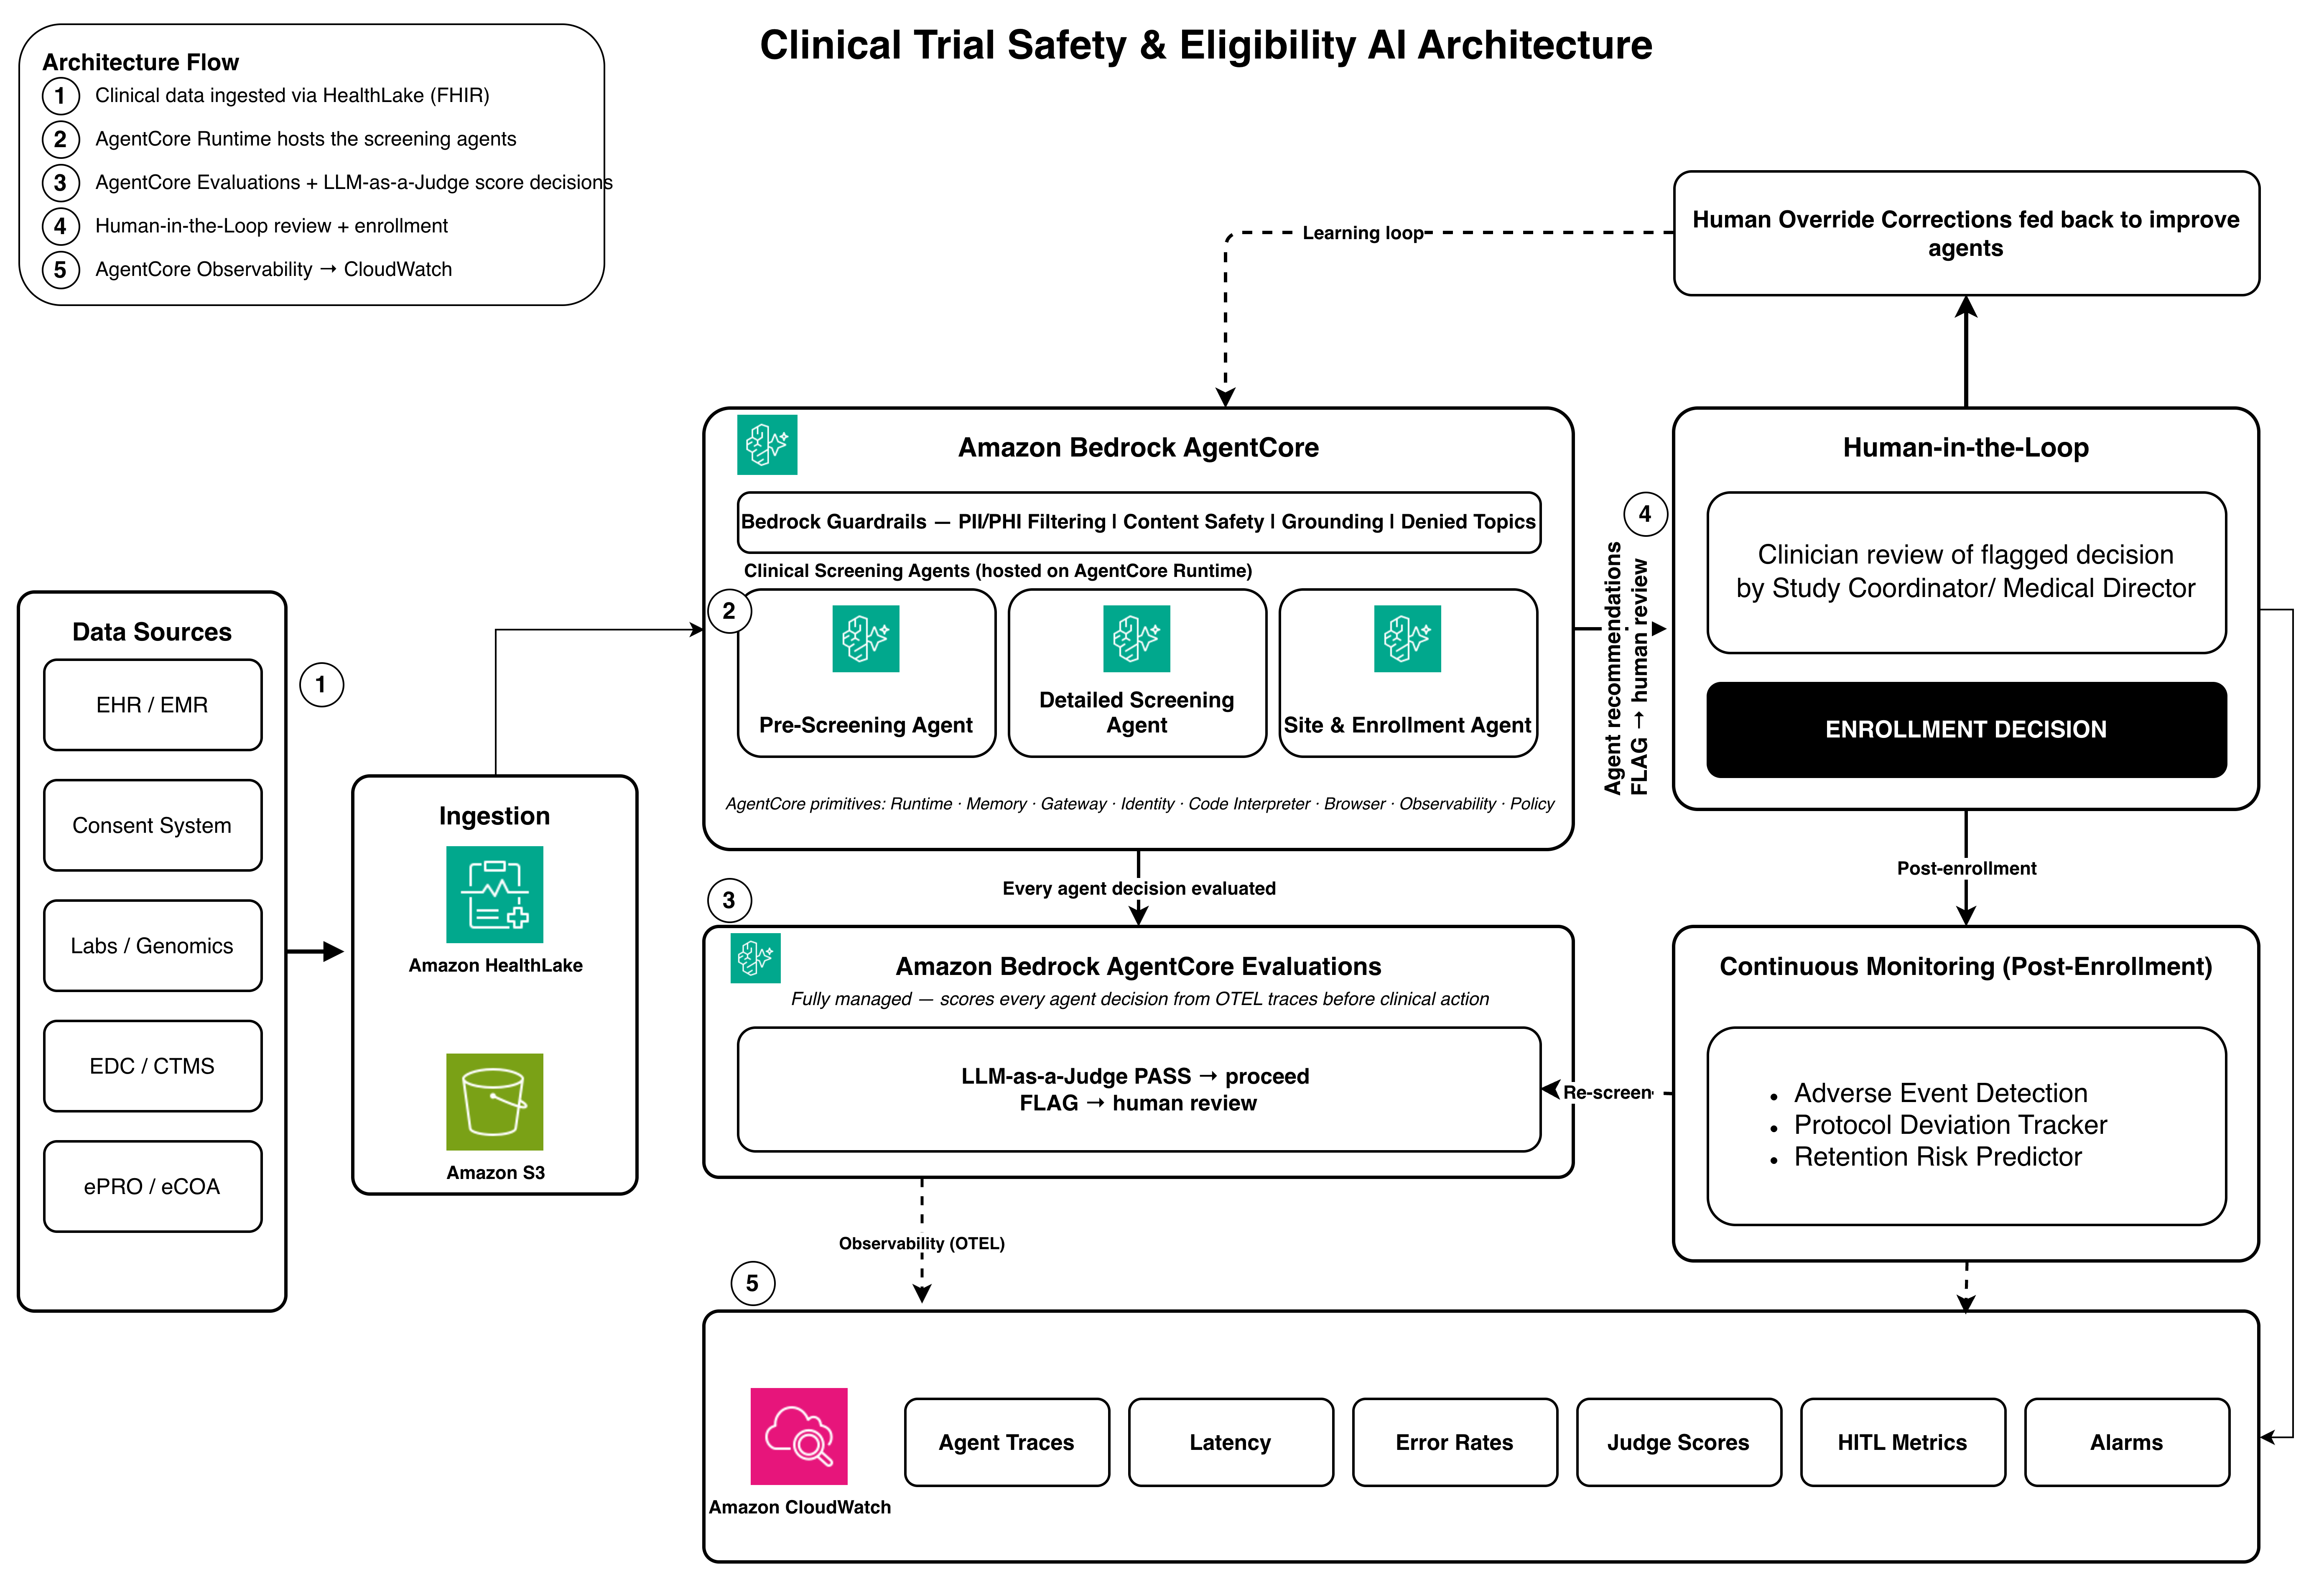
We show how to architect a Clinical Trial Eligibility and Safety Agent on AWS that assembles patient evidence, evaluates it against protocol criteria, and presents screening recommendations with citations, while clinicians retain final authority and full audit trails. It combines AWS HealthLake for FHIR-native data access, Amazon Bedrock AgentCore for multi-step reasoning, and Amazon Bedrock AgentCore Evaluations for scoring each decision via LLM-as-a-judge and human-in-the-loop. This post is for solution architects, engineering teams, and technology leaders applying AI to clinical trial operations on AWS.
AI agents for clinical trial screening
AI agents with Human-in-the-Loop (HIL) are well-suited for clinical trial eligibility and safety decisions because they address information fragmentation while preserving human clinical judgment. The core problem isn’t a lack of data, but that eligibility and safety signals are scattered across EHR notes, lab portals, imaging reports, and medication histories, forcing study teams to reconstruct each participant’s clinical picture. A knowledge graph addresses this by storing clinical data as entities and the relationships between them, representing each patient, molecule, endpoint, and market as a node with relationships stored as edges. To answer an eligibility or safety question, the agent traverses these edges, going from a diagnosis to its associated labs or a medication to its known interactions, rather than re-querying and joining disconnected sources each time. This structure supports the agent’s preparatory work:
Organizing evidence from fragmented sources into a knowledge graph, linking patients, molecules, endpoints, and markets as interconnected nodes.
Mapping patient information against protocol criteria.
Surfacing relevant passages with citations for clinician review.
Highlighting uncertainties that require human judgment.
Critically, the clinician remains the decision-maker. The agent organizes the supporting information. These systems augment rather than replace clinical reasoning — proposing preliminary assessments, flagging edge cases, providing confidence scores, and learning from feedback.
As protocols grow more complex with precision oncology and biomarker-driven eligibility, agents manage multi-step logic and maintain consistency across sites, while deferring final judgment to clinical staff.
Architecture overview
This proposed architecture illustrates how core AWS services can be combined to create an end-to-end clinical trial screening pipeline. AWS HealthLake serves as the FHIR-native clinical data foundation, ingesting and normalizing patient records from disparate EHR systems, lab portals, and imaging archives into a unified, queryable data store. Amazon Bedrock AgentCore orchestrates the multi-step workflow assembling patient profiles, matching them against trial protocols, detecting safety signals, and generating evidence-backed screening recommendations. An Amazon Bedrock Knowledge Bases stores trial protocols, inclusion/exclusion criteria, and safety guidelines. The entire pipeline feeds into a clinician review dashboard where investigators examine agent reasoning, verify citations, and render final decisions. Actions are captured in an immutable audit trail for regulatory compliance.
Architecture diagram showing the clinical trial screening pipeline with AWS HealthLake, Amazon Bedrock AgentCore, and Amazon CloudWatch
Architecture workflow
The screening pipeline operates in the following steps. Each step maps to a distinct phase of the eligibility and safety assessment, from data ingestion through clinician review and continuous monitoring.
Step 1: Clinical data ingestion
AWS HealthLake ingests patient records from EHR systems, lab portals, imaging reports, and medication histories, then normalizes them into FHIR R4 resources for standardized, queryable access.
Step 2: Agent orchestration
Amazon Bedrock AgentCore orchestrates three specialized agents, each scoped to a distinct phase of the screening pipeline. They operate within the Amazon Bedrock AgentCore Runtime, which connects to tools through MCP Gateway, maintains session memory so agents reference earlier findings without re-querying, and enforces identity-based access control for least-privilege data access. A built-in code interpreter handles dynamic calculations such as eGFR or BMI derivation.
Pre-screening agent: The first gate. It resolves three threshold questions: Is the patient’s informed consent valid and current? Does their high-level profile (age, diagnosis category, geography) align with basic enrollment parameters? Have they completed any required washout period? Patients who clear all three advance. Those who don’t receive a documented rejection citing the failing criterion.
Detailed screening agent: The core clinical reasoning engine. It walks through all inclusion and exclusion criteria, retrieving the relevant FHIR resources — Observation for labs, Condition for diagnoses, MedicationStatement for medications — and evaluating each against the protocol threshold. It also reviews organ function, adverse drug reactions, and contraindicated conditions, cross-references medications against the investigational product for interactions, and assesses the overall comorbidity profile for risk combinations no single criterion would catch. The output is a structured determination (Eligible, Ineligible, or Requires Review) with a per-criterion evidence matrix, confidence scores, and a reasoning summary citing source records.
Site & enrollment agent: Once a patient clears screening, it handles operational logistics — matching the patient to the most appropriate site by proximity, capabilities, and investigator availability, then confirming open enrollment capacity. If the preferred site is full, it identifies alternatives and flags the study coordinator.
All three agents operate behind Amazon Bedrock Guardrails, which enforce:
PII/PHI filtering to protect patient health information.
Content safety controls to help prevent clinically inappropriate outputs.
Grounding checks to keep responses anchored in retrieved evidence rather than model parametric knowledge.
Denied topic boundaries to keep agents within their screening scope.
Step 3: LLM-as-judge evaluation
Amazon Bedrock AgentCore Evaluations scores every screening decision using a combination of built-in and custom evaluators across three dimensions:
Clinical accuracy: Correctness of the eligibility determination against patient data, faithfulness to source evidence (not hallucinated justifications), logical coherence across reasoning steps, and context relevance confirming the right protocol and patient records were retrieved.
Operational effectiveness: Response completeness and clarity for coordinators reviewing dozens of patients daily, appropriate use of FHIR queries and knowledge base tools, and end-to-end goal success (did the agent complete the full screening workflow?).
Safety compliance: Custom evaluators verify that safety-critical criteria (lab thresholds, restricted medications, contraindicated conditions) were never skipped, that uncertainties are explicitly acknowledged rather than resolved with false confidence, and that all safety flags route to the appropriate review tier.
Decisions that pass evaluation with high confidence proceed to the clinician dashboard. The system flags those that fall below quality thresholds and routes them to human review with the specific evaluation concern highlighted.
Step 4: Human-in-the-loop review and enrollment
Flagged cases and agent recommendations flow into a tiered clinical review structure:
PI review queue: Principal Investigators review flagged decisions from the LLM Judge, examining the agent’s reasoning chain, verifying citations against source records, and rendering a final determination.
Study coordinator dashboard: Coordinators manage trial logistics, scheduling, and the day-to-day enrollment pipeline, using the agent’s structured outputs to accelerate their workflow.
Patient communication: Outreach and consent updates are coordinated through the dashboard, keeping patients informed of their screening status.
Escalation to medical director: Complex or high-risk cases that exceed the PI’s comfort level are escalated to the Medical Director for final adjudication.
Clinicians retain complete override capability at every stage. When a clinician overrides an agent recommendation, approving a patient the agent flagged or rejecting one it cleared, the system captures the corrected decision and the clinician’s reasoning. These corrections expand the ground truth dataset used by Amazon Bedrock AgentCore Evaluations and surface patterns that inform prompt and retrieval tuning, creating a continuous learning loop where human judgment directly improves agent performance over time.
Step 5: Observability and continuous monitoring
Amazon CloudWatch provides end-to-end observability across all agents, surfacing agent traces (step-by-step execution logs), latency metrics, error rates (failed tool calls, guardrail blocks), judge scores (pass/flag rates per agent), HITL metrics (override rates, review latency), and alarm-based escalation when safety thresholds are breached.
Although the current implementation focuses on screening and enrollment, the same agent orchestration framework, evaluation pipeline, and compliance infrastructure support future post-enrollment monitoring agents such as adverse event detection from lab results and clinical notes, protocol deviation tracking, retention risk prediction, and re-screening triggers when clinical changes affect ongoing eligibility. Each inherits the existing scoring, logging, and auditability without requiring a separate governance framework.
Evaluating agent performance in clinical trial screening with human oversight
The screening pipeline’s credibility rests on two layers: an automated evaluation layer that scores every decision, and a human-in-the-loop (HITL) layer that gives clinicians final authority. LLM-as-Judge (Step 3) decides which cases clinicians see and how they’re prioritized. The HITL workflow (Step 4) decides how clinicians act. Together they form a continuous loop where human judgment both safeguards and improves agent performance. Using Amazon Bedrock AgentCore Evaluations, you build a framework spanning three dimensions: clinical accuracy, operational effectiveness, and safety compliance with built-in and custom evaluators that run continuously.
Clinical accuracy and reasoning
Built-in evaluators check whether the agent gets the determination right and whether its reasoning holds up: Correctness (accurate against the patient’s labs, diagnoses, and medications), Faithfulness (reasoning stays grounded in patient data and protocol, not plausible-sounding invention), Coherence (no logical contradictions across steps), Context relevance (the right protocol and records were retrieved), and Goal success rate (the full workflow ran end to end). Custom LLM-as-Judge evaluators add clinical specifics: Eligibility accuracy (each inclusion/exclusion criterion evaluated correctly) and Criteria coverage (no criteria skipped, especially safety-critical lab thresholds and restricted medications).
Operational effectiveness
Accuracy alone is insufficient, output must fit workflows where coordinators review dozens of patients daily. Helpfulness, conciseness, and relevance confirm a clear, scannable, on-topic determination. Instruction following verifies the expected structured format (patient summary, criteria checklist, determination, justification, safety flags, next steps). Tool selection and parameter accuracy check the agent invoked the right tools with correct inputs.
Safety and responsible behavior
Safety carries the strictest thresholds. Harmfulness detection flags clinically dangerous content; Stereotyping detection makes sure decisions aren’t influenced by demographics beyond protocol requirements. Both trigger immediate review. Custom evaluators target the highest-risk failures: Safety flag detection confirms every significant concern surfaced (contraindicated medications, out-of-range labs, disqualifying conditions, drug interactions), with a single miss treated as critical; Uncertainty acknowledgment makes sure the agent recommends human review on missing or ambiguous data rather than making an overconfident call.
The human-in-the-loop safeguard
When a wrong eligibility call can affect patient safety, human judgment is the final safeguard. A score below threshold routes the case to the HITL workflow.
The three agents together produce an eligibility determination with a confidence score. At trial onset, the clinician sets a confidence threshold. Cases below it or flagged by evaluation reach the clinician dashboard with the specific concern highlighted. Clinicians review the full reasoning and approve, reject, or request more information from the same interface. Their corrections are stored alongside machine-approved records, feeding back into future determinations and continuously improving accuracy.
Review and approval workflow
Review is tiered by complexity: automated pre-screening filters clearly ineligible candidates. Low-complexity cases get expedited review, medium-complexity follow standard protocols, and high-complexity edge cases escalate to senior clinicians. Cases unreviewed beyond set timeframes escalate automatically. Final enrollment decisions, low-confidence cases, experimental therapies, and complex histories require human approval. Routine high-confidence checks proceed automatically.
Audit trails
The system generates immutable audit records in Amazon DynamoDB for every decision, capturing clinician ID, timestamp, patient and trial IDs, outcomes, AI recommendations, and complete workflow execution history. These records are designed to support FDA 21 CFR Part 11 requirements for electronic records and signatures, providing documentation for regulatory inspections and quality assurance. Readers should consult their compliance team and conduct their own assessment. See the AWS compliance resources for further guidance.
Security and compliance
Clinical trial data is among the most sensitive in healthcare. HIPAA, FDA 21 CFR Part 11, GxP, and GDPR require strict controls over how patient data is stored, accessed, and processed, and AI agents reasoning over that data introduce new security considerations. This solution protects data at every layer while maintaining the audit trails and privacy standards regulators require.
AWS HealthLake is HIPAA-eligible with encryption at rest and in transit, access controls, and SMART on FHIR authorization. Amazon Bedrock is HIPAA-eligible, SOC 2 attested, ISO and CSA STAR Level 2 certified, and never shares customer data with model providers. AWS PrivateLink keeps traffic off the public internet.
Amazon Bedrock AgentCore enforces agent boundaries at runtime through declarative authorization policies — readable, deterministic rules, outside application code, defining what the agent can access, invoke, and retrieve. AgentCore runs within your Amazon Virtual Private Cloud (Amazon VPC) for network isolation, and AWS CloudTrail records API calls for an immutable audit trail that can support FDA compliance requirements.
Amazon Bedrock AgentCore Evaluations scores each decision using built-in and custom evaluators with an LLM-as-a-Judge approach. Continuous sampling detects drift, and Amazon CloudWatch alerts teams when quality drops below thresholds — ongoing evidence the agent performs within validated parameters, supporting GxP with minimal manual testing.
Conclusion
In this post, we showed how combining the FHIR-native data foundation of AWS HealthLake with the multi-step reasoning capabilities of Amazon Bedrock AgentCore turns manual, fragmented clinical trial screening into an AI-assisted workflow that reduces patient matching time from days to minutes. Clinical trial enrollment remains one of drug development’s most resource-intensive bottlenecks, and delayed starts carry heavy financial consequences from lost patent-protected sell time and operational burn. Clinicians receive organized evidence, transparent reasoning, and actionable recommendations while retaining full decision authority and audit traceability.
The impact extends beyond speed: more consistent criteria interpretation across sites, earlier detection of safety contraindications, and lower screen failure rates. As oncology trial eligibility criteria grow in complexity — with fewer than 5% of cancer patients enrolling under strict requirements — this human-in-the-loop approach offers a scalable, compliance-aligned path to faster, higher-quality recruitment.
Call to action
Ready to accelerate your clinical trial operations? Take the next step:
Schedule a 30-minute architecture review with our Healthcare and Life Sciences Applied AI specialists to see how Amazon Bedrock AgentCore fits your trial portfolio.
Join other life sciences organizations already transforming enrollment workflows with AWS. Contact us today to begin your journey toward faster, safer, and more efficient clinical trials.
To dive deeper and start building your own solution, explore the following resources:
Cássio De Alcântara is Director, LATAM Sales at Rapid7.
Across Latin America, organizations are embracing cloud, AI, and digital transformation to drive innovation and business growth. These technologies create new opportunities, but also introduce greater complexity and expanding attack surfaces.
In this environment, security leaders are being asked to understand where risk exists across increasingly distributed environments and quickly eliminate blind spots like Shadow IT and Shadow AI – all without adding operational complexity.
To help security leaders and practitioners address this complexity, Rapid7 is excited to announce a new strategic distribution partnership with Licencias OnLine (LOL) across Latin America.
Helping organizations stay ahead of evolving threats
In order to keep day-to-day business operations moving, organizations need security solutions that not only protect critical assets but also support innovation, regulatory compliance, and long-term digital transformation.
Rapid7’s AI-powered cybersecurity operations platform helps organizations strengthen cyber resilience by unifying continuous exposure management, AI-driven threat detection and response, and security automation. By connecting security data across endpoint, cloud, identity, and infrastructure environments, organizations leverage one platform to gain the visibility to reduce risk and act with confidence.
A shared commitment to partner success
Success in today’s fragmented cybersecurity environments depends on a strong ecosystem of partners who can help organizations implement, optimize, and maximize the value of unified security operations.
This is where Licencias OnLine comes in. With a strong, well-established presence across Latin America, deep cybersecurity expertise, and a highly specialized channel ecosystem, Licencias OnLine brings the local knowledge, technical enablement, and operational agility needed to help partners grow their cybersecurity practices and deliver greater value to customers.
Together, Rapid7 and Licencias OnLine will invest in technical training, partner enablement, joint marketing initiatives, and go-to-market programs that help partners expand managed security services, strengthen customer relationships, and accelerate business growth across the region.
Building cyber resilience together
As organizations across Latin America continue to modernize their IT environments, they should have access to security operations that are integrated, intelligent, and designed for today’s AI-powered threat landscape.
Rapid7’s open platform supports this approach through hundreds of technology integrations that help organizations eliminate security silos, improve visibility across their attack surfaces, and automate response workflows. This enables security teams to reduce operational complexity while improving cybersecurity program maturity.
By combining Rapid7’s global cybersecurity innovation with Licencias OnLine’s regional expertise and trusted partner network, this new alliance will make it easier for organizations across Latin America to strengthen cyber resilience while enabling partners to see greater success through measurable business outcomes.
We’re excited to begin this next chapter together and look forward to supporting our partners as they help customers build stronger, more resilient security operations across the region.
You want to build an AWS Step Functions workflow, and you have an AI coding agent open in your terminal or IDE. But the agent doesn’t know about Amazon States Language (ASL), service integrations, or how to deploy state machines. Before you can start, you need to find the right Model Context Protocol (MCP) server package, figure out the configuration format for your specific agent, and set up credentials.
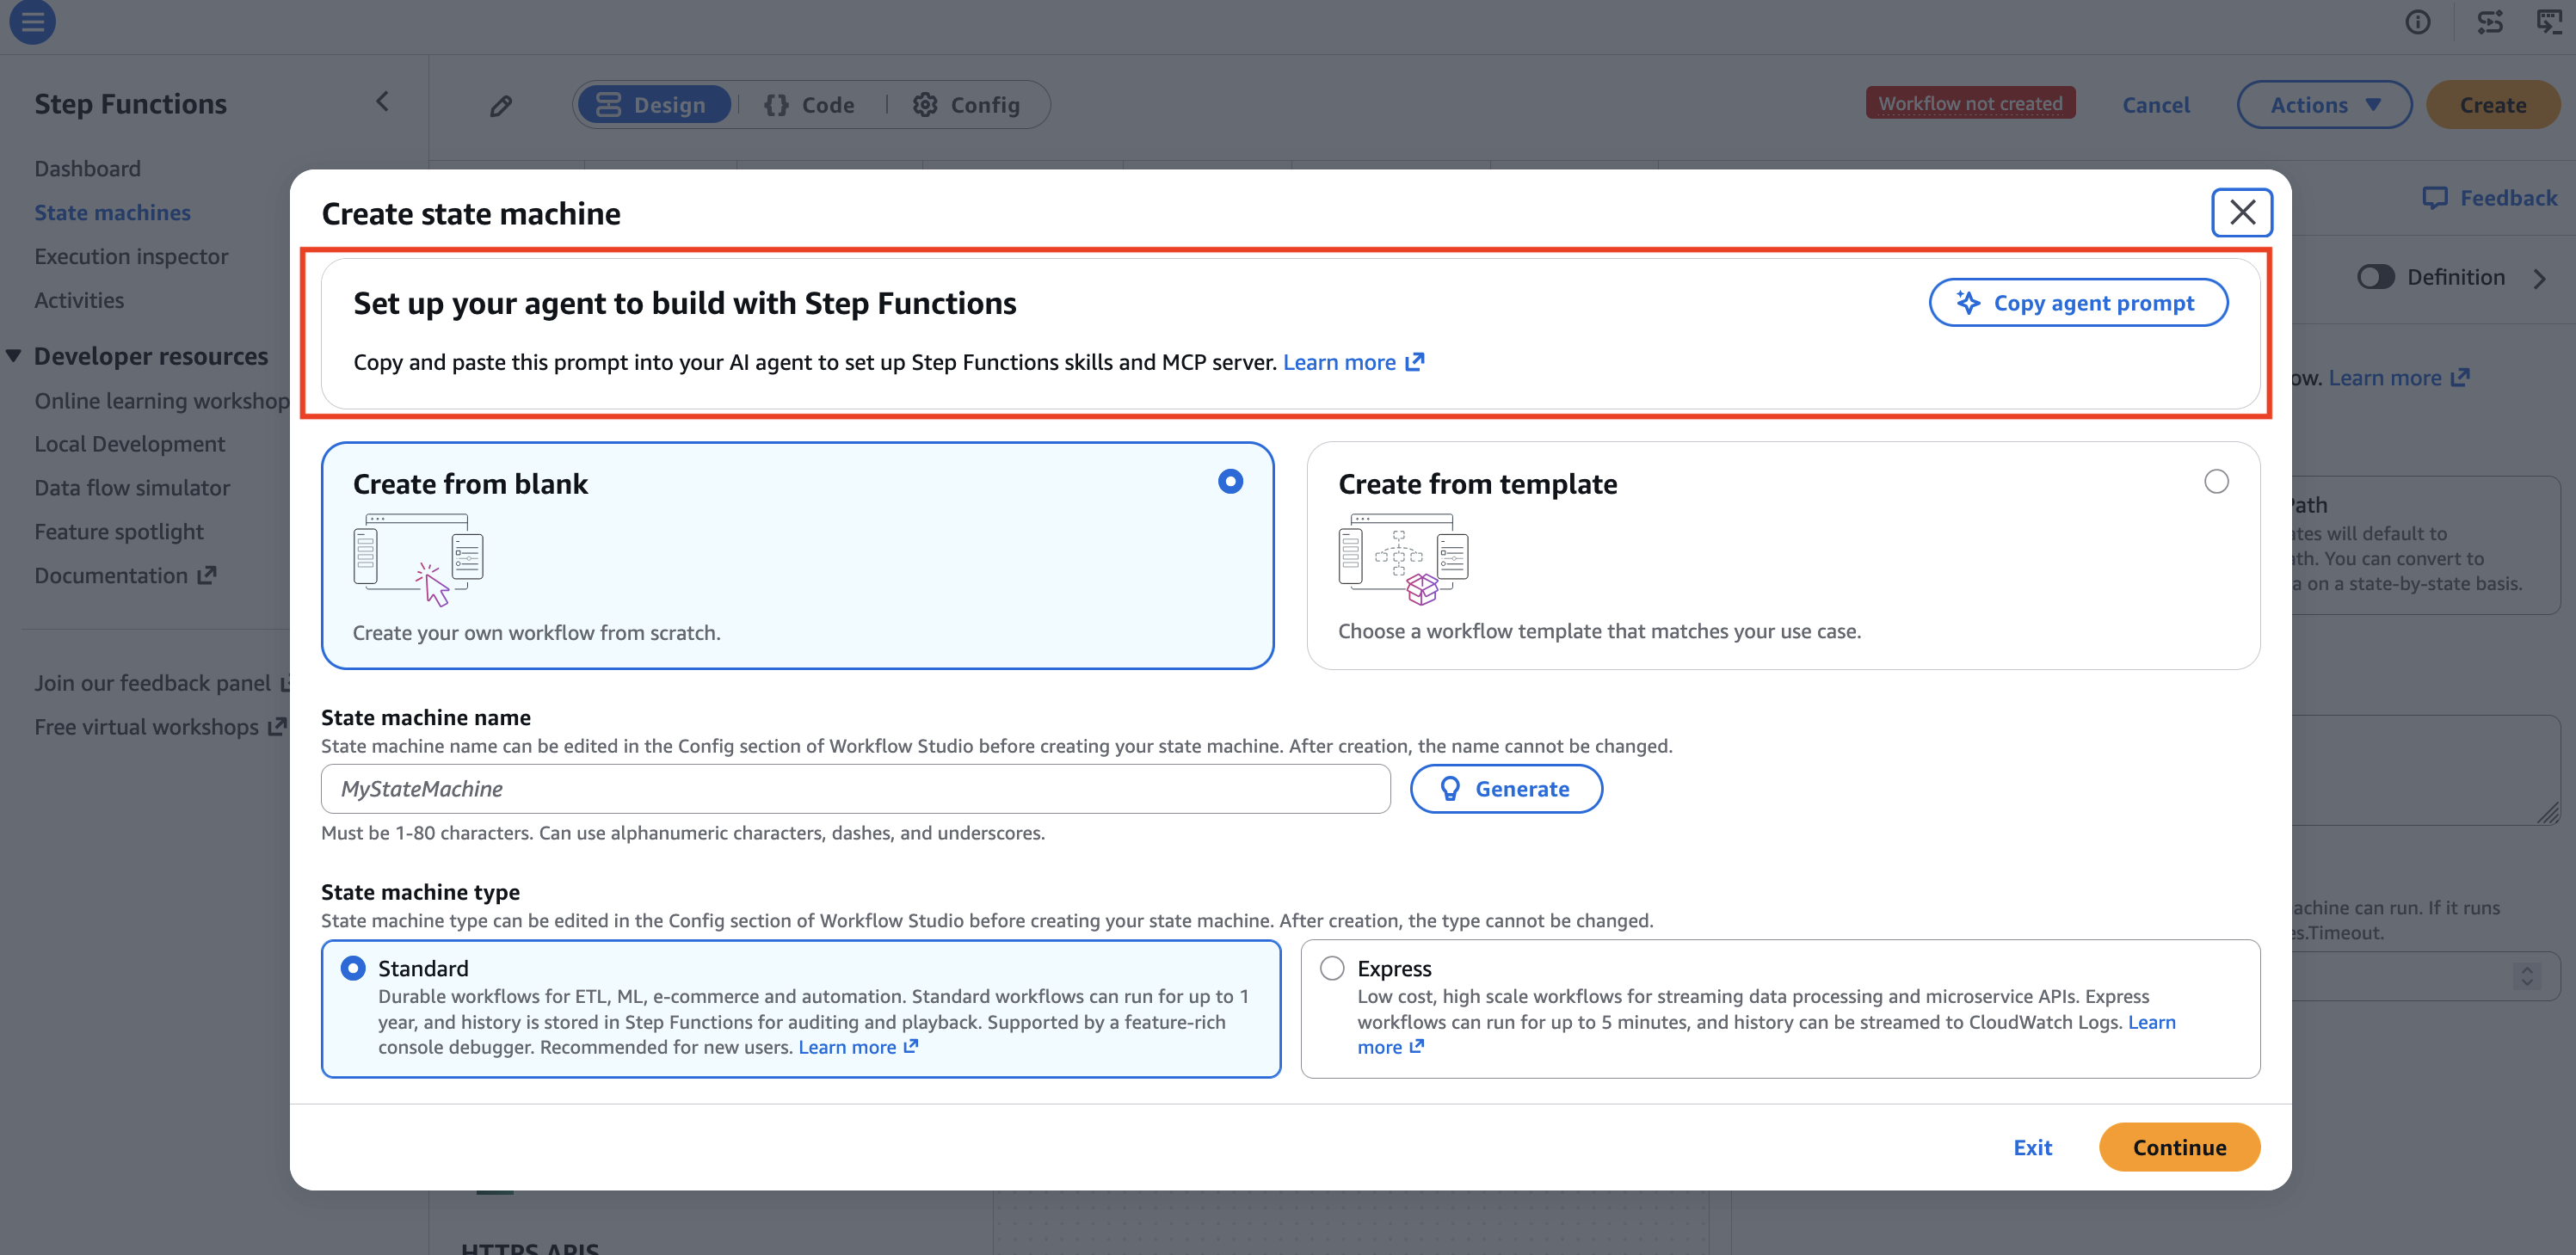
AWS Step Functions has added a “Copy agent prompt” button to the AWS Step Functions console that removes this setup entirely. You choose the button, paste the prompt into your agent, and the agent configures itself with Serverless skills and an MCP server. You can start building workflows with natural language immediately. The feature works with Claude Code, Kiro CLI, Cursor, GitHub Copilot, Codex, Devin Desktop, OpenCode, and any other MCP-compatible agent.
How it works
The button appears in three places in the Step Functions console:
The home page, under “How it works”.
The Create State Machine modal (at the top, before you begin building).
The Local Development section on the home page.
Here’s an example from the Create State Machine flow:
Open the Step Functions console and choose Create state machine.
At the top of the modal, you see the banner: “Set up your agent to build with Step Functions. Copy and paste this prompt into your AI agent to set up Step Functions skills and MCP server.”
Choose Copy agent prompt. The console copies a fetch instruction to your clipboard.
Paste the prompt into your AI agent’s chat or terminal.
The agent reads the setup guide and self-configures.
The copied prompt is a fetch instruction that points to a setup guide hosted on AWS documentation. You paste it into your agent, and the agent installs two things:
AWS Serverless skill (from the Agent Toolkit for AWS) provides your agent with deep context on Step Functions. It includes how to write ASL, structure workflows with retries and error handling, choose between Standard and Express workflow types, implement patterns like saga orchestration and parallel fan-out, and deploy using AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).
AWS Serverless MCP Server gives your agent direct access to AWS. Through the Model Context Protocol, your agent can create and update state machines, start and describe executions, inspect workflow history, and manage resources in your account.
Supported agents
The setup guide auto-detects your agent and provides the correct configuration format:
Claude Code: Installs through the plugin marketplace and registers the MCP server with claude mcp add.
Kiro CLI: Writes to ~/.kiro/settings/mcp.json.
Codex: Registers with codex mcp add.
Cursor: Writes to .cursor/mcp.json.
GitHub Copilot: Writes to .vscode/mcp.json.
Devin Desktop: Writes to .devin/mcp_config.json.
OpenCode: Writes to ~/.config/opencode/opencode.jsonc.
If you use a different MCP-compatible agent, the guide provides a generic JSON configuration block you can add to your agent’s config file.
What you can build
Once your agent is configured, you can describe workflows in natural language, and the agent produces valid, deployable state machines. Here are a few examples:
Order processing with compensation: “Build a workflow that validates a payment, reserves inventory and sends a confirmation email. If payment fails, release the inventory reservation.”
Parallel fan-out: “Create an Express workflow that calls three AWS Lambda functions in parallel, waits for all to complete, and merges the results into a single response.”
Human approval gate: “Add a step that pauses the workflow and waits for a manager to approve before proceeding with the deployment.”
Error handling: “Add retry with exponential backoff and a maximum of three attempts to the payment processing step. If all retries fail, route to a fallback notification step.”
Because the agent has the MCP server connected, it can also deploy the workflow directly to your account, start test executions, and inspect the results without leaving the agent interface.
Advantages
Always current: The Agent Toolkit for AWS content stays up to date as Step Functions adds new features, integrations, and patterns. When you run the prompt, your agent gets the latest skills and configurations automatically.
No context switching: You stay in your agent’s interface for the entire workflow: design, build, deploy, test, and iterate. No switching between the console, documentation, and your editor.
Works with your existing credentials: The MCP server uses your local AWS profile. No new AWS Identity and Access Management (IAM) roles or permissions are required beyond what you already use for Step Functions development.
Agent-agnostic: Whether you use Claude Code, Kiro, Cursor, Copilot, or another tool, the same button and prompt works. You don’t need to find agent-specific setup instructions.
Choose Copy agent prompt from the banner (on the home page under “How it works,” in the Local Development section, or in the Create State Machine modal).
Paste the prompt into your AI coding agent.
Start describing the workflow you want to build.
This feature is available in all commercial AWS Regions at no additional cost. To learn more about the setup process, see the agent setup guide. For more on the Agent Toolkit for AWS, see the GitHub repository. For AWS MCP Servers, see the documentation.
We’d like to hear how you use this feature. Tell us about it in the comments.
Version
154.0 of the Firefox browser has been released. Changes include
extending local network access protections to WebSocket connections, more
flexible, per-site configuration of cookie and data clearing, and more.
When deploying AI agents with Amazon Bedrock AgentCore, organizations benefit from built-in modern support for OAuth 2.0, AWS Identity and Access Management (IAM), and API key authentication through Amazon Bedrock AgentCore Gateway. However, some enterprise environments still use legacy authentication mechanisms such as HTTP Basic Authentication (Basic Auth) (RFC 7617). The extensible architecture of AgentCore Gateway enables support for these authentication mechanisms through a request Lambda interceptor—custom code that runs each time an agent calls a tool.
In this post, we show you how to use a request Lambda interceptor to authenticate to a downstream tool API using system credentials, retrieving a service account credential from AWS Secrets Manager and constructing a Basic Auth header. This design keeps credentials isolated from the agent, designed to mitigate exposure through model-driven behavior such as prompt injection.
Important: Basic Auth is an antiquated technology that transmits credentials as Base64-encoded text and should not be used as a long-term authentication strategy. AWS recommends modernizing to OAuth 2.0, SAML, OpenID Connect, or IAM where possible. However, some organizations with legacy workloads choose to decouple authentication modernization from their agentic AI adoption, addressing each on independent timelines. If your environment requires Basic Auth integration as an interim measure, consult your AWS Solutions Architect to evaluate the security trade-offs before proceeding. We’re providing this post as a reusable implementation, but it shouldn’t be construed as an endorsement of Basic Auth, or considered suitable as a long-term solution.
Solution overview
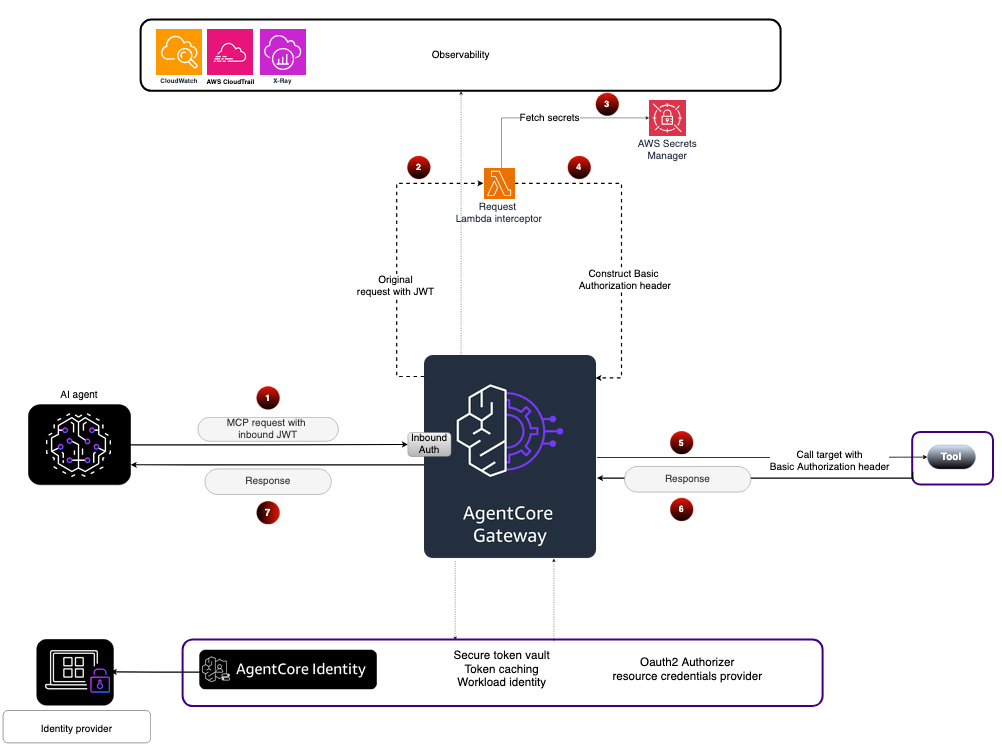
The solution uses a request Lambda interceptor in AgentCore Gateway to retrieve system credentials and construct a Basic Auth header for the downstream tool API. Figure 1 shows the end-to-end flow.
Figure 1: Solution workflow
The AI agent initiates a tool call over Model Context Protocol (MCP) to the gateway with an inbound JSON Web Token (JWT) issued by a configured identity provider (IdP). The MCP request body contains the tool name and any required parameters. The gateway’s inbound authentication layer validates the token against the IdP specified in the inbound authorizer configuration.
After inbound authentication succeeds, the gateway invokes the request Lambda interceptor, passing the original request payload and headers, including the validated JWT and its embedded claims.
The request Lambda interceptor re-validates the inbound JWT issued by the configured IdP as a defense-in-depth measure, then retrieves the system service account credential from Secrets Manager. The credential is a service account that authenticates the AI agent to the downstream tool.
The interceptor then constructs a compliant Basic Auth header using the system credential and adds it to the outbound request. Because Basic Auth transmits credentials as Base64-encoded text (not encrypted), you must implement relevant compensating controls (e.g., ensure that all communication with the downstream tool API is over TLS, conduct two-person review of Lambda code changes, and so on).
Note: The system credential stored in Secrets Manager corresponds to a service account in Active Directory (AD). The credential lifecycle requires a one-time manual seed: a system administrator creates the service account in AD and stores the same initial credential in Secrets Manager (necessary because Secrets Manager can’t read a password back from AD). As a security best practice, trigger an immediate rotation after seeding to retire the human-known password using the built-in capabilities of Secrets Manager. From that point forward, Secrets Manager automates the rotation process, periodically generates a new password, and updates both Secrets Manager and AD simultaneously. This eliminates manual credential management in either system. At runtime, the request Lambda interceptor retrieves the current credential from Secrets Manager and presents it to the downstream tool, which validates it against AD. For implementation details on keeping both stores synchronized, seeRotate Active Directory credentials stored in AWS Secrets Manager.
The AgentCore gateway forwards the adjusted request now carrying the custom authentication header to the downstream target tool.
The downstream target tool authenticates the request, processes it, and returns the response to the gateway.
The gateway relays the response back to the AI agent.
Step 1: Attach a request Lambda interceptor to your AgentCore Gateway
Configure the AgentCore gateway to invoke a request Lambda interceptor for authentication transformation before forwarding the request to the downstream tool.
Important: You must enable passRequestHeaders configuration. Without it, the request Lambda interceptor can’t receive the request header containing the inbound JWT, and the authentication pattern described in this post will not work.
The following example shows the gateway configuration:
The interceptor independently validates the JWT signature as a defense-in-depth measure, protecting against scenarios where the request Lambda interceptor could be invoked through a path that bypasses gateway validation. It fetches the identity provider’s JSON Web Key Set (JWKS) (cached across warm Lambda invocations to avoid repeated network calls), verifies the token’s signature, expiration, and issuer, then returns the decoded claims.
Step 3: Retrieve system credentials from Secrets Manager
The interceptor retrieves the system service account credential from Secrets Manager. This credential authenticates the AI agent to the downstream tool. The secret is encrypted with a customer-managed AWS Key Management Service (AWS KMS) key and cached in memory for the configured time-to-live (TTL) to minimize API calls while ensuring rotated credentials are picked up promptly.
The following code retrieves the credential from Secrets Manager:
  import boto3
  secrets_client = boto3.client('secretsmanager')

  def get_system_credentials():
      """Retrieve the system service account credential from Secrets Manager."""
      response = secrets_client.get_secret_value(
          SecretId=os.environ['SYSTEM_CREDS_SECRET_NAME']
      )
      return json.loads(response['SecretString'])
IAM permissions: The interceptor’s execution role requires secretsmanager:GetSecretValue scoped to the specific secret Amazon Resource Name (ARN), and kms:Decrypt scoped to the KMS key used to encrypt it. Follow the principle of least privilege by restricting the resource ARN rather than using wildcards.
Note: The agent doesn’t have access to Secrets Manager. Only the request Lambda interceptor—a deterministic function not influenced by model behavior—retrieves credentials. This isolation is designed to mitigate the risk of adversarial prompts instructing the model to access or exfiltrate authentication credentials, even if the agent is compromised.
Step 4: Construct the Basic Auth header
The request Lambda interceptor constructs the Basic Auth header using the system credential retrieved for the downstream tool.
The following code shows the core transformation logic.
  def build_system_auth_header(headers):
      """Validate JWT and construct Basic Auth header with system credential."""
      auth_header = headers.get('Authorization', '')
      if not auth_header.startswith('Bearer '):
          return _error_response(401, "No Bearer token found in request.")

      # Validate JWT (defense-in-depth)
      claims = validate_jwt(auth_header[7:])
      if not claims:
          return _error_response(401, "JWT validation failed.")

      # Retrieve system credential from Secrets Manager
      creds = get_system_credentials()

      # Construct Basic Auth header (RFC 7617)
      basic_auth_encoded = base64.b64encode(
          f"{creds['username']}:{creds['password']}".encode()

      ).decode()
      headers['Authorization'] = f"Basic {basic_auth_encoded}"
      return headers
Conclusion
A request Lambda interceptor in Amazon Bedrock AgentCore Gateway can bridge the gap between the authentication patterns supported by the gateway and the authentication requirements of legacy tool APIs that haven’t yet migrated to modern authentication standards. As demonstrated in this post, the interceptor validates the inbound JWT, retrieves system credentials from Secrets Manager, and constructs the downstream tool’s Basic Auth header without modifying tool schemas or agent implementation.
This approach is an interim integration pattern, not a target architecture. It introduces a credential that must be synchronized between Secrets Manager and the tool’s identity store (such as Active Directory), adding operational overhead for rotation, drift detection, and lifecycle management. The recommended path is to modernize the downstream tool to accept OAuth 2.0, SAML, or OpenID Connect, eliminating stored credentials entirely. Until that modernization is complete, the interceptor isolates credential handling from the agent runtime, designed to help ensure that the agent—a non-deterministic system influenced by user prompts—does not have access to authentication secrets.
If you have feedback about this post, submit comments in the Comments section below.
In this post, you learn how to run fast analytical queries directly against raw log and trace data in Amazon OpenSearch Service using PPL and SQL.
Amazon OpenSearch Service is a fully managed service that helps you deploy, scale, and operate OpenSearch, the open source suite for search, analytics, and observability in the AWS Cloud. OpenSearch Service powers search and real-time analytics workloads, from lexical and hybrid search to log analytics and observability. This post focuses on log analytics, and on a practical question: how much analytical work can you do directly against raw log and trace data, without moving it or reshaping it first?
The new optimized engine in OpenSearch Service answers that question: you can point Piped Processing Language (PPL) and Structured Query Language (SQL) queries at raw log and trace data. The engine returns aggregations, filters, and scans over billions of events on the data exactly as you ingested it. In this post, you follow a single incident investigation, one query at a time. You see how the engine answers each new question, from multi-dimensional breakdowns and latency distributions to error rates and fleet sizing. No precomputed structure sits behind the results.
How the optimized engine queries raw data
The optimized engine stores data in the columnar Apache Parquet format and runs queries through Apache DataFusion, a vectorized execution engine, with Apache Calcite planning each query. Because the engine stores data in columns, an analytical query reads only the columns it touches and processes their values in batches, instead of reading each matching document in full. Alongside the columnar format, the engine also keeps an inverted index on the same data, so the query planner routes each operation to the path that serves it best: the columnar engine for aggregations and analytical scans, and the inverted index for selective search and filtering.
You ingest your logs and traces through the same Bulk API and clients you use today, and you write PPL or SQL against them as they land.
An investigation, one query at a time
The following walkthrough traces a common observability use case, root-cause analysis during a live incident, from the perspective of a site reliability engineer (SRE). The engineer notices elevated latency and a handful of error alerts, with nothing that points to a clear cause. No existing dashboard covers this particular shape of problem, so the engineer opens Amazon OpenSearch Service and starts asking questions of the raw trace data, letting each answer decide the next one. PPL suits this work well. Each command transforms the data and passes it to the next, so the engineer reads a query left to right the same way they think through the investigation.
The walkthrough uses generated OpenTelemetry (OTEL) data from a synthetic load generator, at billion-document scale. The focus is the query capability, that is, what the engineer can express and retrieve directly from raw spans, rather than the specific values in each result.
Step 1: Assess the scope
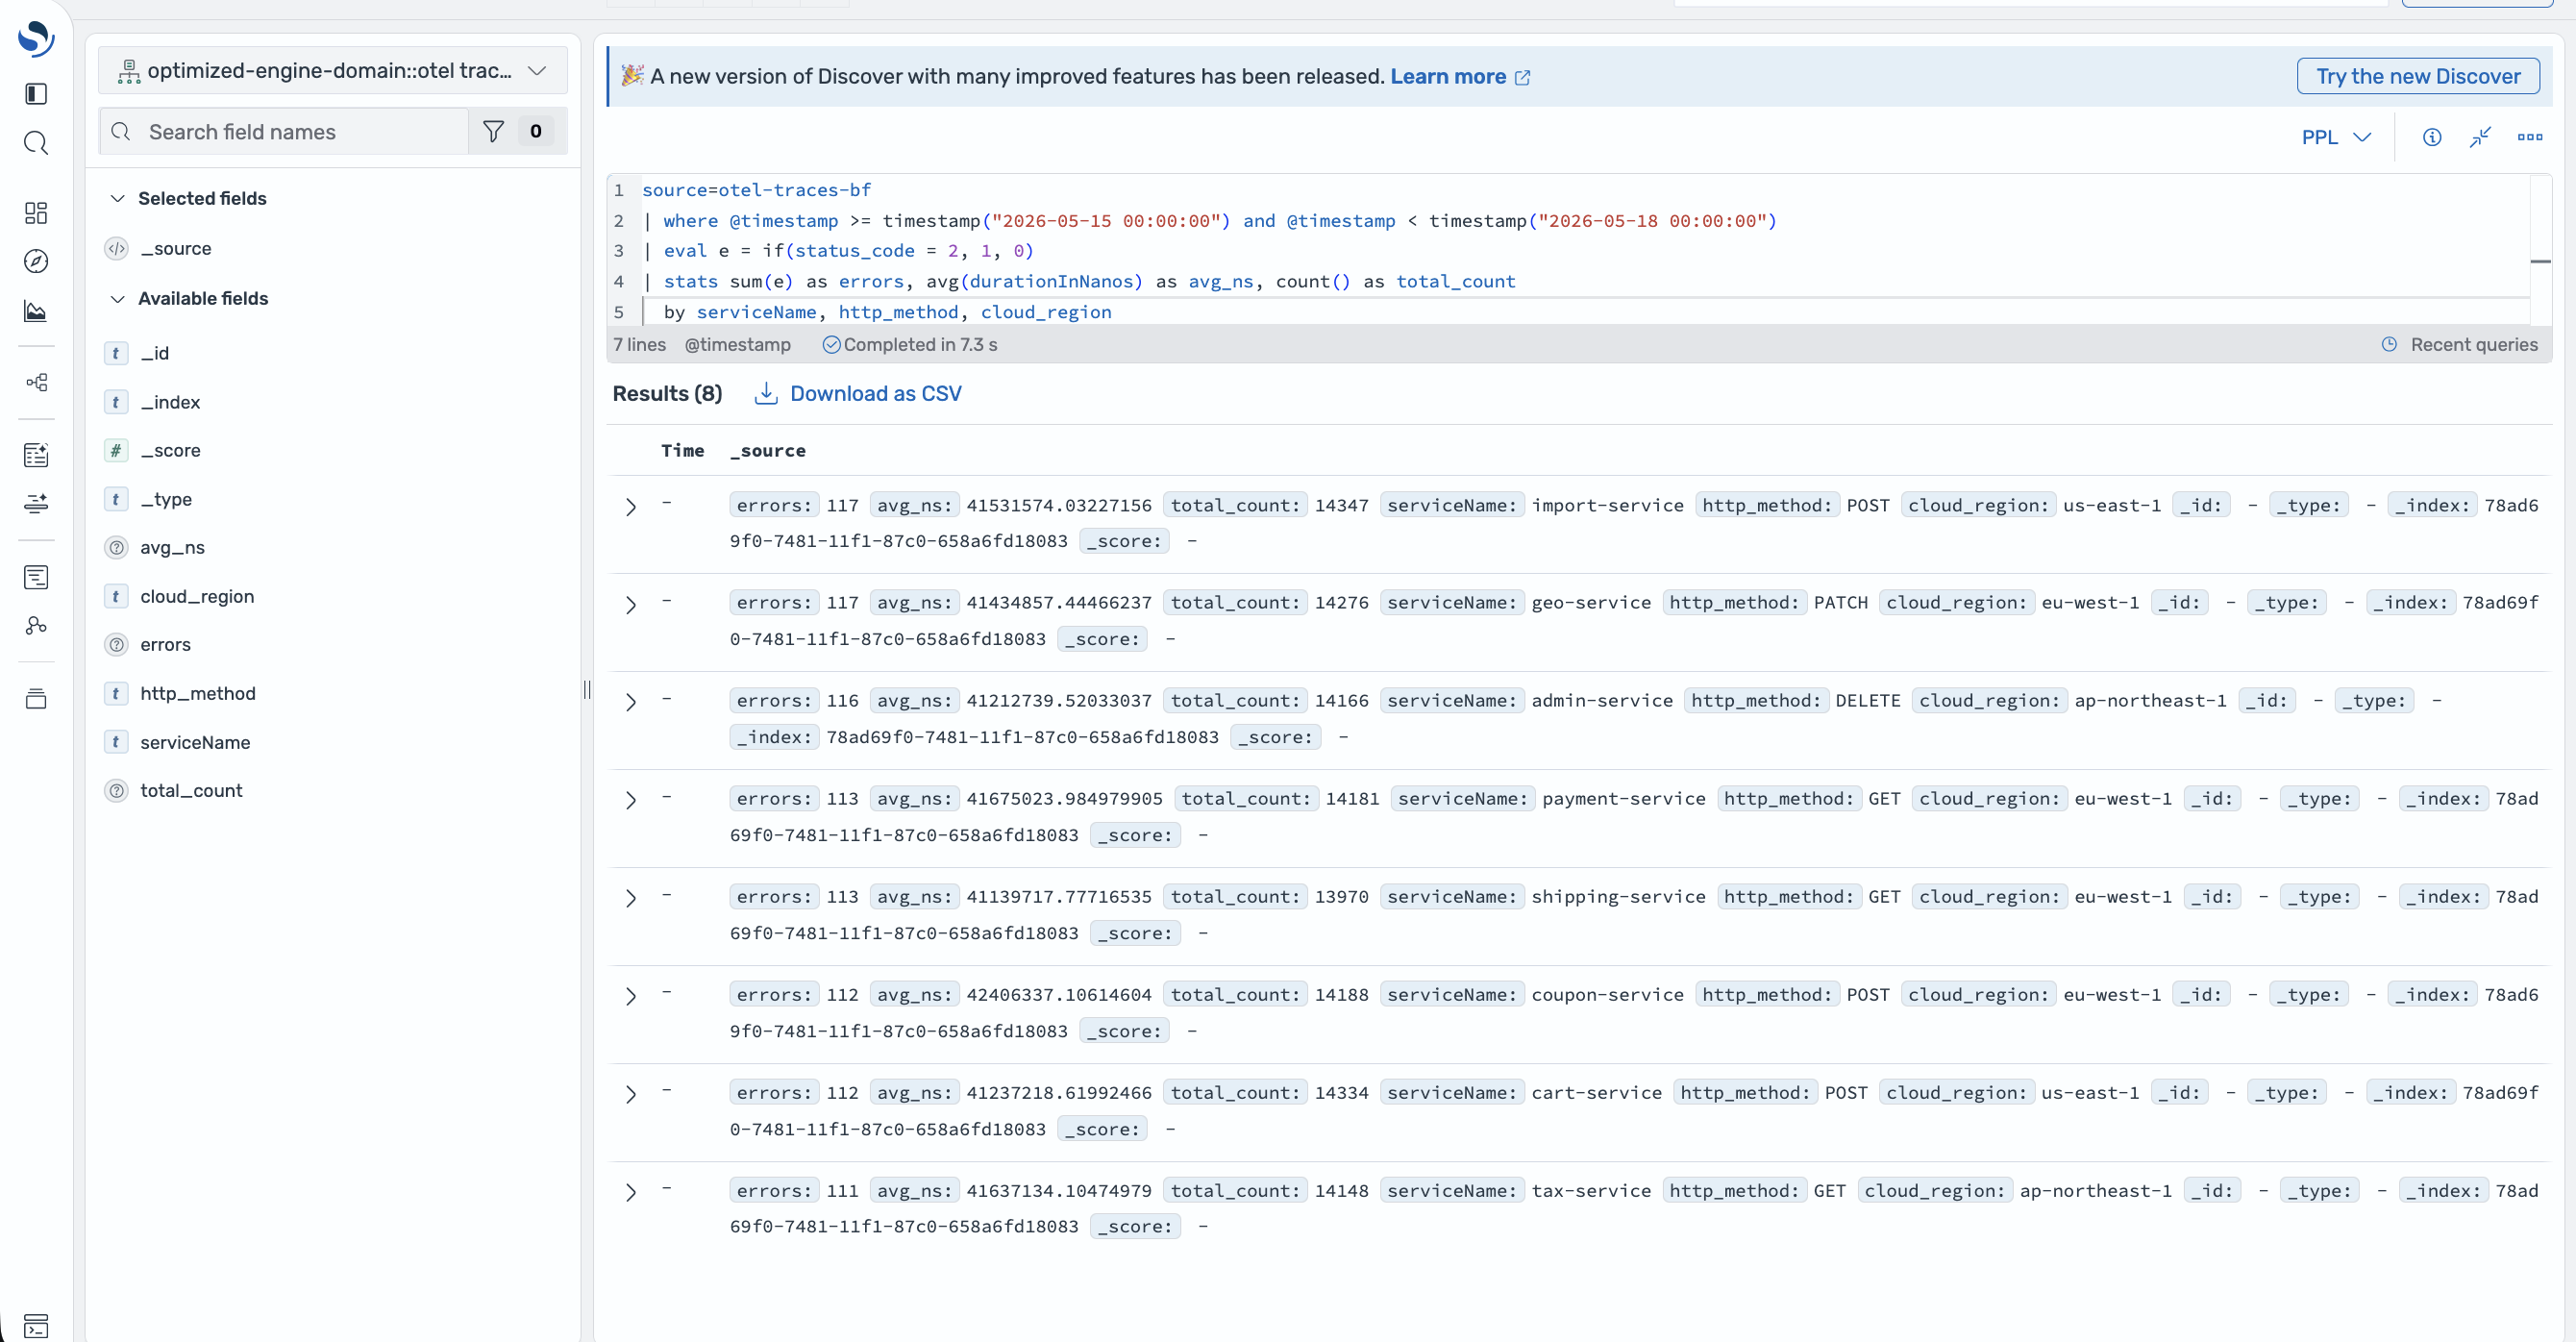
The first question in any investigation is how widespread the signal is. The engineer breaks errors down across service, HTTP method, and cloud Region in a single pass over roughly 1.1 billion spans.
source=otel-traces
| where @timestamp >= timestamp("2026-05-15 00:00:00") and @timestamp < timestamp("2026-05-18 00:00:00")
| eval e = if(status_code = 2, 1, 0)
| stats sum(e) as errors, avg(durationInNanos) as avg_ns, count() as total_count
  by serviceName, http_method, cloud_region
| sort - errors
| head 8
In plain terms, this query answers the engineer’s first question: where are the failures happening? It counts the error spans and breaks them down by service, HTTP method, and AWS Region in a single pass. Rather than guessing which service to open first, the engineer gets a ranked list of the hardest-hit combinations to investigate.
errors
total_count
avg_ns
serviceName
http_method
cloud_region
730
112,436
41,246,806
export-service
GET
us-west-2
722
111,215
41,000,227
catalog-service
PUT
eu-central-1
704
112,051
41,295,539
image-service
PATCH
us-west-2
612
93,214
41,451,145
healthcheck-service
PUT
us-east-1
609
94,314
41,418,897
auth-service
POST
us-east-1
609
94,414
41,447,444
email-service
PATCH
ap-northeast-1
593
89,726
41,047,114
payment-service
PUT
eu-central-1
581
89,854
41,195,643
file-service
PUT
ap-northeast-1
The errors spread across services, methods, and Regions, which points to a systemic pattern rather than a single misbehaving service.
Step 2: Check whether one host concentrates the failures
The spread could still reflect one saturated node or a fleet-wide condition. To tell the two apart, the engineer groups failures by exception type, service, and host across the entire index, with no time filter to narrow the scan.
source=otel-traces
| where isnotnull(exception_type)
| stats count() as total_count by exception_type, serviceName, host_name
| sort - total_count
| head 8
total_count
exception_type
serviceName
host_name
6
DeadlockDetectedException
notification-service
ip-10-0-16-34
6
IllegalStateException
api-gateway
ip-10-0-180-234
6
FileNotFoundException
cart-service
ip-10-0-90-162
6
ConnectionRefusedException
feature-flag-service
ip-10-0-8-123
5
TimeoutException
auth-service
ip-10-0-97-78
5
ConcurrentModificationException
order-service
ip-10-0-165-15
5
TimeoutException
coupon-service
ip-10-0-158-25
In this sample the counts are low and every row lands on a different host, so no single node stands out. This points to a fleet-wide pattern rather than one bad machine. On production data the same query makes the distinction directly: a code-level bug shows up across many hosts, whereas a single failing node concentrates its errors on one host_name.
Step 3: Quantify the latency distribution per service
Next, the engineer pulls a latency profile for each service. This includes count, average, minimum, and maximum duration, to see how each one behaves and how wide the spread runs.
source=otel-traces
| where @timestamp >= timestamp("2026-05-15 00:00:00") and @timestamp < timestamp("2026-05-18 00:00:00")
| stats count() as total_count, avg(durationInNanos) as avg_ns, min(durationInNanos) as min_ns, max(durationInNanos) as max_ns
  by serviceName
| sort - total_count
| head 8
serviceName
total_count
avg (ns)
min (ns)
max (ns)
event-bus
11,087,263
41,249,552
26,113
9,304,132,159
scheduler-service
9,175,964
41,251,927
21,919
13,432,040,933
cdn-service
9,173,572
41,225,385
23,468
13,768,293,306
ml-inference
9,036,753
41,289,101
40,410
14,625,084,517
compliance-service
8,274,635
41,294,694
41,915
7,462,983,016
metrics-collector
7,804,234
41,334,728
16,535
23,228,217,669
notification-service
7,688,714
41,204,635
51,562
8,695,311,374
image-service
7,674,406
41,248,069
47,473
15,350,500,299
This gives the engineer a latency fingerprint for each service: the averages sit near 41 milliseconds. But the multi-second maxima reveal a long tail consistent with requests queuing behind a slow dependency.
Step 4: Measure the error rate per service
To track a service-level objective, the engineer computes the error rate (errors against total requests) per service. The query uses an inline conditional, followed by a grouped sum and count, and a final division to produce the error rate.
source=otel-traces
| eval is_err = if(status_code = 2, 1, 0)
| stats sum(is_err) as errors, count() as total_count by serviceName
| eval error_pct = round(100.0 * errors / total_count, 2)
| sort - error_pct
| head 8
errors
total_count
error_pct
serviceName
699,358
22,415,308
3.12
payment-service
647,811
26,880,140
2.41
checkout-service
562,811
30,096,860
1.87
auth-service
316,192
24,510,990
1.29
cart-service
288,314
30,671,704
0.94
order-service
202,612
28,140,552
0.72
search-service
186,012
33,820,415
0.55
catalog-service
134,722
35,453,247
0.38
image-service
The engineer defines the error-rate metric in the query itself, and the engine computes it across the full index. The busiest paths, payment and checkout, run near 3 percent, whereas some services stay below 1 percent.
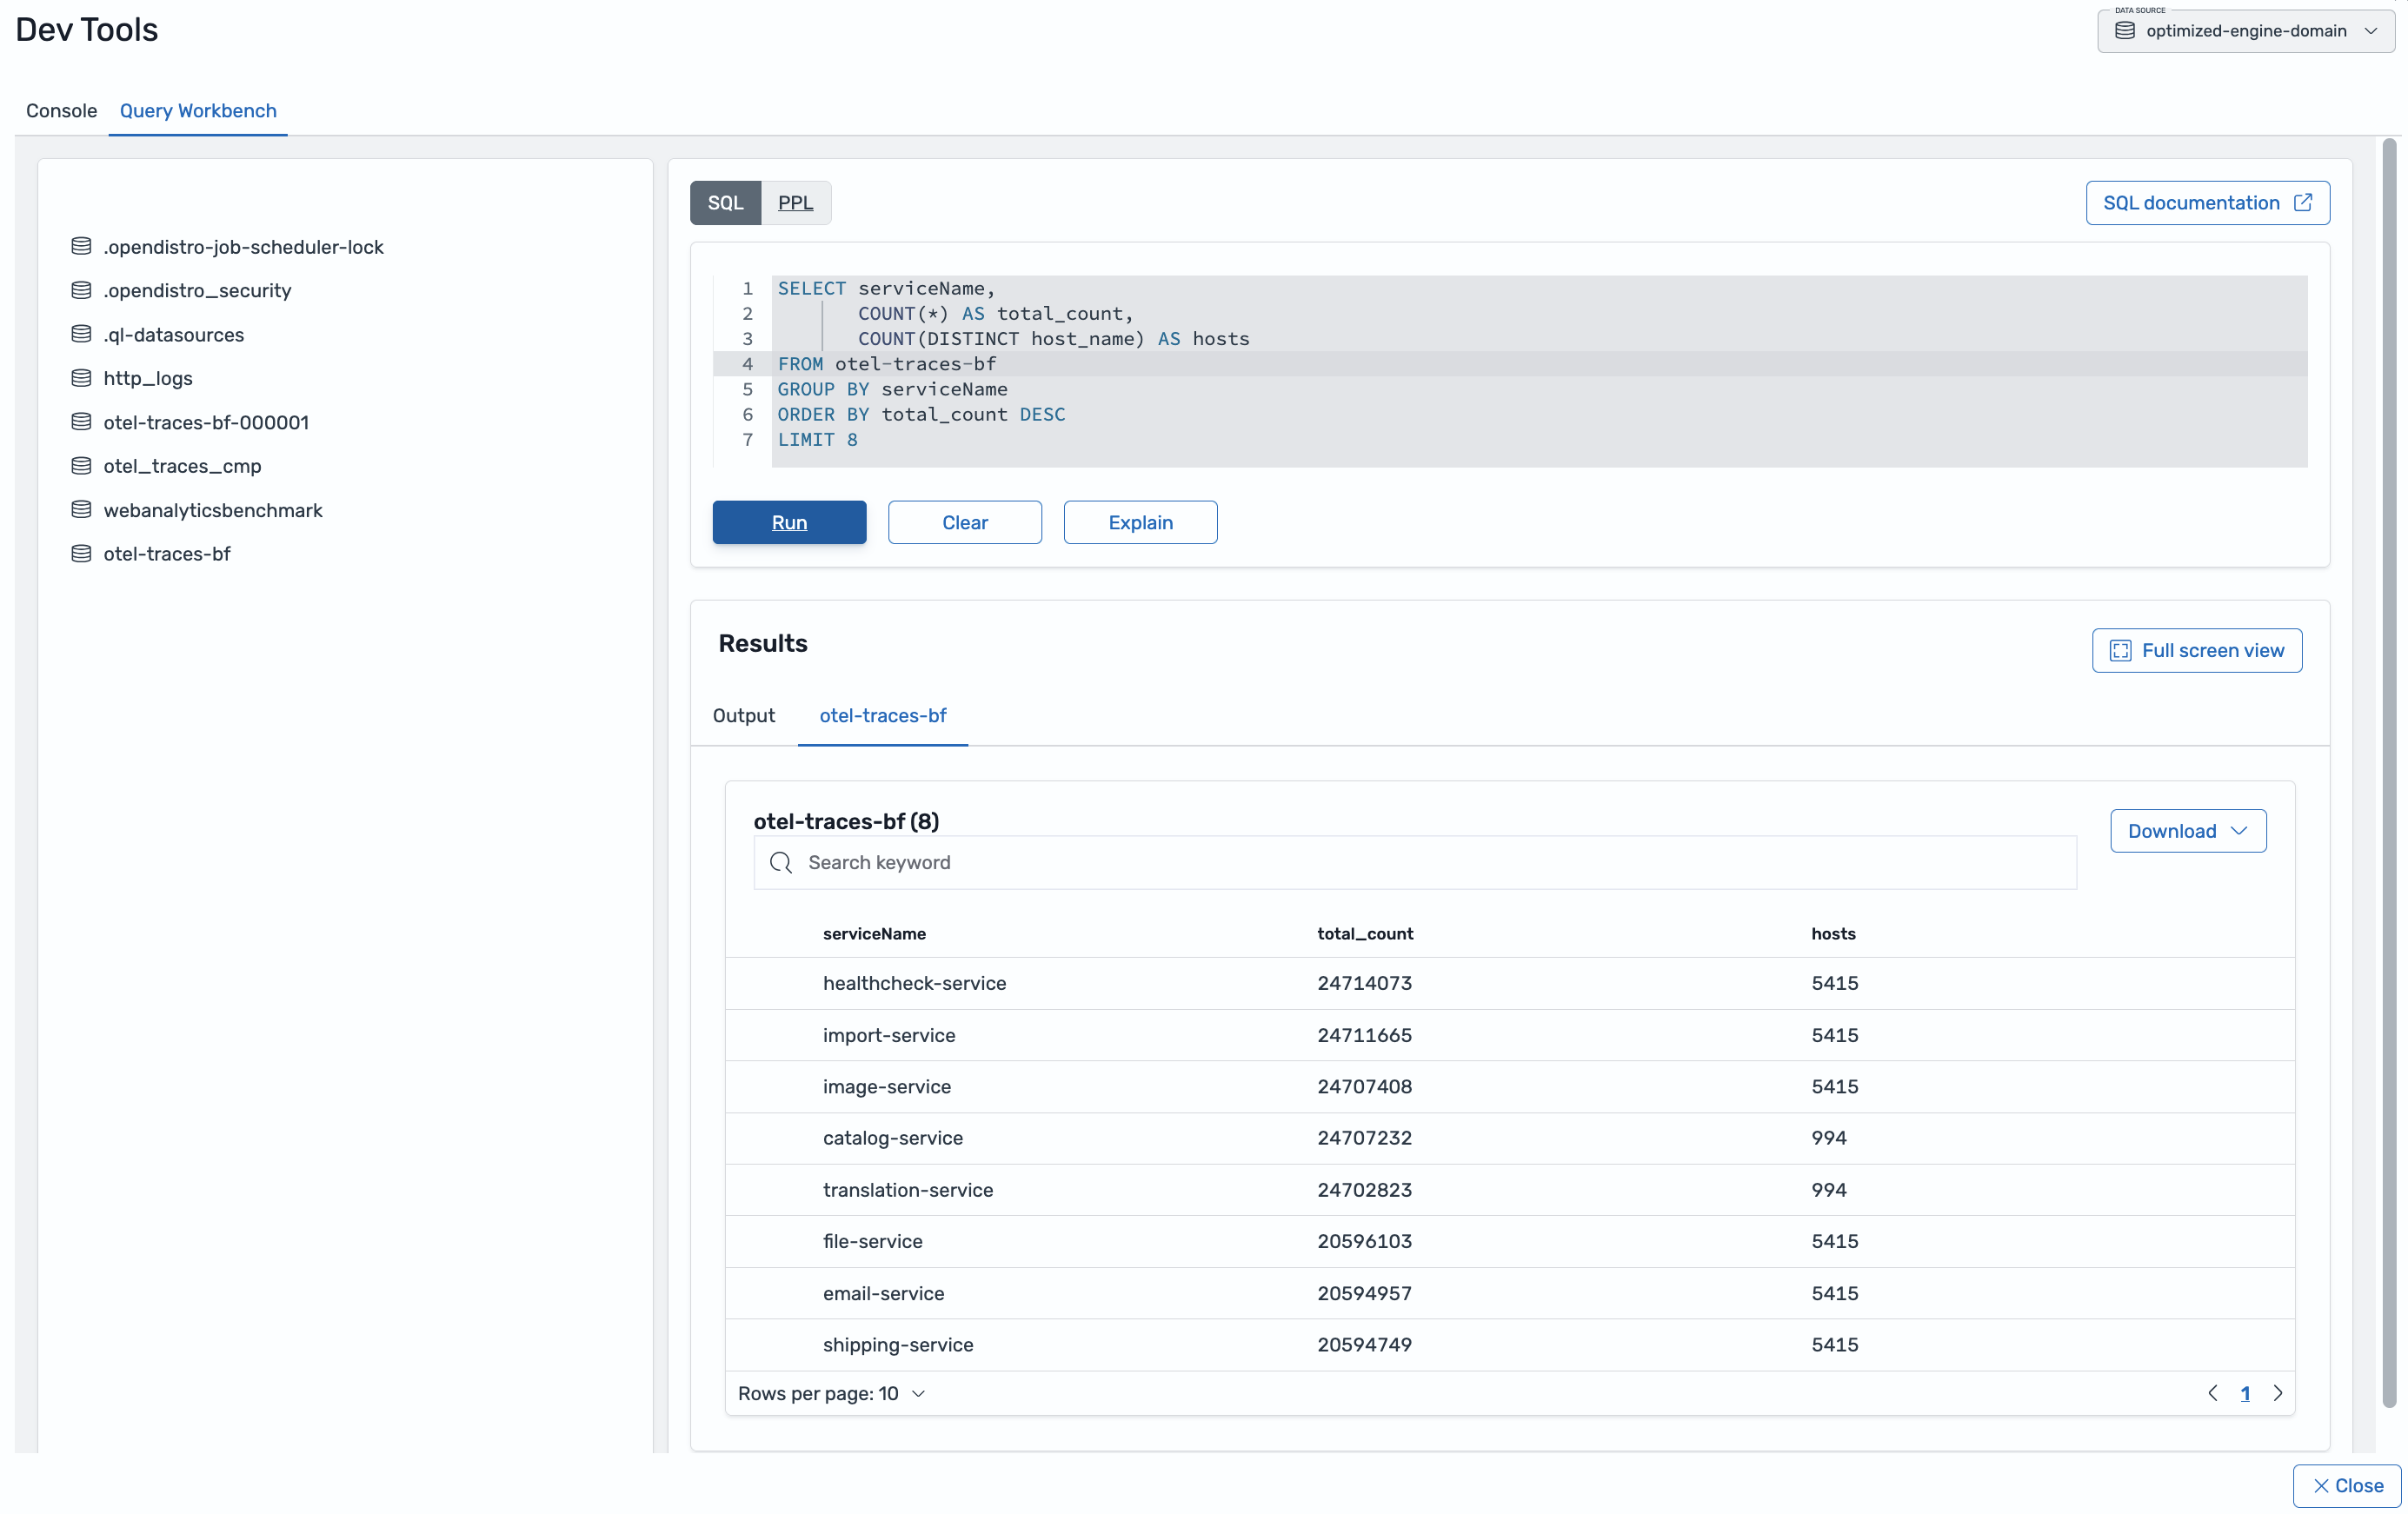
Step 5: Size the fleet footprint with SQL
Finally, the engineer sizes how much of the fleet each service spans, a capacity and impact question, and switches from PPL to SQL to express it.
SELECT serviceName,
       COUNT(*) AS total_count,
       COUNT(DISTINCT host_name) AS hosts
FROM otel-traces
GROUP BY serviceName
ORDER BY total_count DESC
LIMIT 8
serviceName
total_count
hosts
ml-inference
35,481,688
2,535
image-service
35,453,247
2,491
email-service
35,443,569
2,517
shipping-service
30,700,372
2,438
translation-service
30,490,570
2,502
auth-service
30,096,860
2,466
chat-service
25,564,111
2,449
recommendation-service
25,366,844
2,483
The query runs a COUNT(DISTINCT) over a high-cardinality field at billion-row scale, and switching languages mid-investigation costs the engineer nothing more than writing SQL instead of PPL. The host counts cluster in the approximately 2,400–2,540 range, so each service runs across a broad slice of the fleet. That confirms the earlier finding: the errors reflect a fleet-wide pattern, not a single node.
The engineer asked five questions and ran five queries, and each answer shaped the next. The optimized engine served every query directly from raw trace data, across both PPL and SQL, without a rollup table or precomputed summary behind any result.
Run these queries where you already work
You don’t need a separate tool to run the queries in this walkthrough.
Figure 1: Investigation queries and results grid in Query Workbench
Query Workbench in OpenSearch Dashboards UI gives you a dedicated editor for PPL and SQL. You write a query, run it, and read the results in a grid, using the same queries shown throughout this post. When you want to move from a written query to interactive exploration, Discover runs the same PPL and SQL against your indexes. In Discover, you can filter, expand fields, and drill into individual documents without leaving the page. The same query language works in both places, so you can start an investigation in Discover and carry it into Query Workbench, or the reverse, without rewriting anything.
Figure 2: PPL query and field list in Discover
Keep all your data and query it as it is
Querying raw data directly only helps if you can afford to keep the raw data. The optimized engine compresses observability data up to 70 percent more efficiently than the default General Purpose engine. That compression turns “keep everything and query it directly” into a practical default. You retain full-fidelity data for the questions you cannot predict in advance. You also pay less to store it than you would to store the raw JSON.
Get started
To try the optimized engine, create an Amazon OpenSearch Service domain running OpenSearch 3.5 or later. Then select the Observability use case during setup, which provisions the domain with the optimized engine.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.