Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=BxoHfHmAqDU
(Не)познатият дявол на тревожността и депресията
Post Syndicated from original https://www.toest.bg/nepoznatiyat-dyavol-na-trevozhnostta-i-depresiyata/

Когато за пръв път се сблъсках с безсънието, реагирах като истински българин и не отидох на лекар, защото не смятах, че съм луд. Преди да ми се случи това нещо, което стана през не особено приятната за мен 2011 година, се отнасях доста скептично към депресията и не можех да разбера как това, че си тъжен, е болест. Подобно на мнозина смятах, че човек трябва да се стегне, да не мрънка и да търпи.
Всичко това – при положение че имам фамилна предразположеност към тази болест. Както се казва, на чужд гръб и сто тояги са малко, а докато не ти дойде до главата, не знаеш за какво става дума. Можем да продължим с българските народни глупости, но истината е, че при среща с психичното заболяване първоначално сме като
в небрано лозе
Затова и едно състояние, което може би има възможност да се овладее навреме, започва да се влошава, докато не стане хронично. Което не означава, че човек постоянно страда, но симптомите понякога се завръщат, както знаем от Стивън Кинг. Докато отида на доктор, изчерпах всички други възможности, включително да проверя дали не ми е направена магия. Поне не съм давал пари – разчитах на приятели, безплатно предлагащи ми експертността си в областта на окултното.
Междувременно взе да ми става ясно, че както казваше Дънкан Маклауд в увода на сериала „Шотландски боец“, не съм сам и има и други като мен. В новина, излязла по-рано тази година, вестник „24 часа“ ни ощастливи, че полудяваме и вече над един милион българи страдаме от тревожност. В статията с това гръмко заглавие има любопитна информация за зачестяването на психичните диагнози и обострянето на ситуацията предвид пандемията от коронавирус. Истината е, че още преди забелязах колко се чака за психиатричен преглед, та не е като да няма интерес. Помня, че когато препоръчвах лекарката, оправила положението при мен, на други мои закъсали приятели, майка ми каза, че това не е ресторант, та да го споделям наляво и надясно. Аз обаче смятам, че отърваването ми от активните симптоми на генерализираната тревожност, каквато се оказа моята диагноза, ме оставя с известен дълг да говоря по въпроса. Вече съм изгубил броя на приятелите, търсещи ме за съвет, след като разберат, че съм преживял такова нещо, и не считам за позорно да споделям.
Тези заболявания бележат ръст не само в България, но и по целия свят
Донякъде е заради стресовия живот, който водим, донякъде обаче е и защото вече започваме да говорим по-свободно за тези проблеми, без страх, че ще ни осъдят. Започва да се разбира, че да кажеш на някого с психично страдание „да се стегне“ е като да очакваш някой с навехнат крак смело да стъпи върху него.
В този текст ще обърна внимание на „по-леките“ състояния, които все още се приемат за „лигавщини“ – тревожност, депресия, безсъние, обсесивно-компулсивно разстройство, панически атаки. Те сериозно влошават качеството на живот и изискват, освен посещение при специалист, и по-спокойно говорене за тях. Най-малкото е добре страдащият да не получава подигравки. Искам да дам няколко практически съвета и добри примери какво да се прави при среща с тези болести. Със сигурност не е добра идея да се ходи на врачка, да се леят куршуми, да се викат духове и т.н. Молитвата, която духовниците препоръчват, може да помогне, но не и да замени квалифицираната помощ.
И така, първо. Ако се случи на вас
Най-важното, което трябва да се знае, е, че тревожността по принцип е нормална и дори полезна реакция, мобилизираща човека да се справи с трудна ситуация. Подобно е и с тъгата – при загуба на близък, раздяла с любим човек, разваляне на старо приятелство е напълно нормално да си потиснат. Проблем има, когато не можеш да изключиш от този режим, а тревожността и депресията са толкова силни, че пречат на ежедневните ти дейности. Безсънието например те оставя изтощен и отчаян, неспособен да се справиш със служебните ангажименти и да си пълноценен в общуването с близките. Паническата атака също е разтърсваща и преживелият я става боязлив и притеснен. Познавам човек, който ми призна, че навремето е смятал оплакванията ми от депресия за несериозни, но рязко променил мнението си за психическите заболявания, когато преживял паническа атака. „Помислих, че ще пукна“, сподели той с мен твърде живописно, макар и лаконично.
В такива моменти всякакви съвети трудно достигат до човека, но е важно да се знаят две основни неща. Въпреки клишето за лудите, няма нещо ненормално да имаш подобни оплаквания. Вижте заглавието на „24 часа“ – над милион сме! Ако се обединим в партия, може да победим и евентуалната бъдеща формация на Румен Радев. Шегата настрана, не бива да се притеснявате, че това, което става с вас, е срамно. Нито е безнадеждно, както и да изглежда в момента. Днес медицината е доста напреднала и ако хапчетата от романите на Агата Кристи действително са били изключително опасни и смъртоносни (в книгите ѝ героите взимат барбитурати, днес ползвани главно за анестезия и лечение на епилепсия), в наши дни медикаментите, ако изобщо се стигне до тях, са по-щадящи. Въпреки това човек не бива да се самолекува, а да намери специалист, на когото да се довери. Какъв да е той, според мен е индивидуално. Аз лично имам нужда от някой по-внимателен и прощаващ, при други хора по-добре действа някой по-строг. Добрият психолог или психиатър обаче е подготвен да прецени какъв подход е правилният за вас.
В обобщение, да имате такава болест нито е срамно, нито е необичайно. Тя може да се преодолее, но с подходящата помощ. Не е речено при първата безсънна нощ да хукнете по специалисти, но ако видите, че положението се влошава, не отлагайте.
Второ. Ако се случи на близък
Това е доста по-сложно, макар грижата за друг човек да е силно мотивираща. Най-важното е да успеете да видите, че нещо не е наред. Рискови групи са почти всички, но специално внимание заслужават младите хора, при които тези болести обикновено започват да се проявяват със симптоми, често обяснявани с пубертета: загуба на интерес към любими дейности, занемаряване на външния вид, влошаване на успеха в училище. Понякога зад тях се крие нещо по-лошо. За мен особено рискова група са мъжете, тъй като те не са свикнали да споделят за такива проблеми. При тях те могат да се проявят нетипично (с гняв), а също и да завършат трагично – макар да опитват по-рядко самоубийства, при мъжете обикновено тези опити са ефективни.
Най-важното е човек да бъде изслушан, без да бъде осъждан и укоряван. Да не се дават празни и банални съвети, като това да „мисли позитивно“, а по-скоро да се изрази разбиране („Това, което преживяваш, е наистина ужасно, съчувствам най-искрено“). Да не се внушава чувство за вина („Празник е, а ти разваляш настроението на всички“). Да бъде насочен към специализирана помощ с акцент, че така може да получи облекчение на страданията си.
Важно е, когато помагате на друг, да не пренебрегвате напълно себе си и своите нужди. Нито вие, нито обектът на грижите ви ще спечели, ако също се поболеете. Не се чувствайте гузни, ако си открадвате време да прекарате добре, на кафе с приятели или на кино. Това даже е задължително. Животът не е и не бива да бъде само страдание.
Трето. Какво да правим като общество
Това е въпросът за един милион лева (или половин милион евро, живот и здраве от догодина). Истината е, че човечеството като цяло сравнително отскоро започва да се запознава с природата на тези заболявания, да развива клонове от фармакологията, заделени за тях, да създава методи за подкрепа, разбиране и справяне с проблема. Най-важното е за тези състояния да не се мълчи, защото те засягат голям брой хора, които остават с впечатлението, че са черни овце и са оставени сами с мъката си, която никой не разбира. Затова е много важно, че известни хора като актьора Даниел Радклиф или пилота от Формула 1 Ландо Норис говорят по темата за психичното здраве открито, като признават уязвимостта си. Така те могат да помогнат на свои фенове също да бъдат по-честни.
В България все още сме по-назад, но напоследък нещата се променят, за което свидетелства и появата на сериал като „Тревожност“ по-рано тази година.
За повече чуваемост може да се предприемат няколко стъпки
Първо, от страна на медиите. Необходимо е да се отделя повече време за този проблем. Май е обявен за месец на хората с психически проблеми, но не получава и една десета от вниманието към юни, който е за правата на ЛГБТ хората. Това не е критика към вторите, още повече че те също са в рисковите групи на „празнуващите“ през май, а по-скоро че няма внимание към първите. Повече статии, повече добронамерени материали са необходими, по възможност без крещящи заглавия като онова, че полудяваме дружно.
Второ, от страна на образователната система. Тук е добре по някакъв начин децата да научат, че тези състояния съществуват, че могат да засегнат всеки, но също и че в повечето случаи могат да бъдат преодолени. Това не важи само за психическите болести – болките в кръста също са широко разпространени, но аз например го научих сравнително наскоро; преди това смятах, че в моето семейство пак сме си нещо кекави. Като цяло е добре младите хора да имат базова информация за предизвикателствата пред здравето си, в това число и психическото. Как това ще се съчетае с часовете по религия и добродетели, засега не е ясно.
Трето, от страна на работодателите. Повече разбиране за хора с такива оплаквания, повече яснота за бърнаута, който ги прави нетрудоспособни или опасни за себе си и околните. Докато следвах, научих, че по време на индустриализацията във Великобритания някакъв търговец осъществил голям пробив, когато разбрал, че работниците му – парадоксално – са по-продуктивни, когато имат повече свободно време. Стигнали ли сме нивото на този индустриалец?
Четвърто, от страна на масовата култура.
Психическите проблеми всъщност са сравнително популярен неин аспект, особено на запад. Прави се обаче честата грешка психичните заболявания да се представят като нещо чудовищно (лошия от „Тексаското клане“) или да се фетишизират като нещо привлекателно (Харли Куин и Жокера от „Отряд самоубийци“). Това не е изцяло лошо, тъй като все пак вкарва проблема в обращение, но не го представя правдиво и затруднява реалните страдащи, които едва ли са с изящно оформени тела – всъщност лекарствата за страданията им обикновено водят до качване на килограмите.
Разбира се, има и страхотни примери за сериозни драматични филми, като „Красив ум“ с Ръсел Кроу и „Солистът“ с Робърт Дауни-младши. Тях обаче не всеки ги гледа, тъй като темата не е от най-леките и приятните, а и са посветени на това, което личната ми терапевтка наричаше „голямата, страшната болест“ – шизофренията. Затова не е зле по-меките състояния да бъдат вплитани ненатрапчиво в популярни произведения, така че засягането им да не звучи дидактично, а човешки да представи проблема. Отличен пример е „Хари Потър и Орденът на феникса“, петата книга от поредицата на Дж. К. Роулинг. Макар никъде да не е посочена диагноза на главния герой, гледан от отказващи всякакво разбиране негови роднини, той проявява класически симптоми на преживяна травма, тъй като е бил свидетел на смъртта на свой съученик (Седрик) в предишната книга. Много интересни са коментарите на пораснали читатели, които споделят, че като тийнейджъри са се дразнили на гневните му изблици и на внезапната промяна на поведението му, но като възрастни изпитват съчувствие и разбиране към него.
Епичният фентъзи роман Dragon Mage от М. Л. Спенсър пък предлага историята на герой, който, подобно на самата авторка и на сина ѝ, има аутизъм. Диагнозата отново не е спомената, но вместо това са показани гледната точка на персонажа, различното му мислене, но също и уменията му по свой начин да бъде силен, да обича, да помага, да греши.
Леките психически заболявания са проблем, който е с нас, за да остане. Имаме два варианта за реакция. Единият е да си заровим главите в пясъка като щрауси и да смятаме суеверно, че ако наложим табу над темата, подобни болести няма да ни застигат. Това е магическо мислене, доказано неефективно. Затова идва вторият вариант – да започнем да говорим на тази тема спокойно, честно и смело, така че да я демистифицираме. Най-силният страх на човека, казва писателят Хауърд Лъвкрафт, е този от неизвестното. Поради тази причина, ако ние превърнем депресията и тревожностите в „познат дявол“, те ще спрат да ни притесняват толкова и ще станат напълно победим противник.
Eight stable kernels released
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1023793/
Security updates have been issued by AlmaLinux (git, krb5, perl-CPAN, and rsync), Debian (tcpdf), Fedora (libmodsecurity, lua-http, microcode_ctl, and nextcloud), Red Hat (osbuild-composer), SUSE (389-ds, avahi, ca-certificates-mozilla, docker, expat, freetype2, glib2, gnuplot, gnutls, golang-github-teddysun-v2ray-plugin, golang-github-v2fly-v2ray-core, govulncheck-vulndb, helm, iperf, kernel, kernel-livepatch-MICRO-6-0_Update_2, kernel-livepatch-MICRO-6-0_Update_4, krb5, libarchive, libsoup, libsoup2, libtasn1, libX11, libxml2, libxslt, orc, podman, python-Jinja2, python-requests, python3-setuptools, python310, python311, python39, rubygem-rack, sslh, SUSE Manager Client Tools, SUSE Manager Client Tools and Salt Bundle, ucode-intel, util-linux, and wget), and Ubuntu (libvpx, linux, linux-aws, linux-aws-hwe, linux-gcp, linux-gcp-4.15, linux-hwe, linux-kvm, linux-oracle, linux, linux-aws, linux-azure, linux-gcp, linux-gke, linux-gkeop, linux-ibm, linux-intel-iotg, linux-kvm, linux-lowlatency, linux-nvidia-tegra, linux-oracle, linux, linux-aws, linux-kvm, linux-aws, linux-lts-xenial, linux-aws-fips, linux-azure-fips, linux-fips, linux-gcp-fips, linux-aws-fips, linux-gcp-fips, linux-azure-fde, linux-fips, and linux-intel-iot-realtime, linux-realtime).
1942 Battle of Dutch Harbor
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=7LZavCu-Atc
The Ramifications of Ukraine’s Drone Attack
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/06/the-ramifications-of-ukraines-drone-attack.html
You can read the details of Operation Spiderweb elsewhere. What interests me are the implications for future warfare:
If the Ukrainians could sneak drones so close to major air bases in a police state such as Russia, what is to prevent the Chinese from doing the same with U.S. air bases? Or the Pakistanis with Indian air bases? Or the North Koreans with South Korean air bases? Militaries that thought they had secured their air bases with electrified fences and guard posts will now have to reckon with the threat from the skies posed by cheap, ubiquitous drones that can be easily modified for military use. This will necessitate a massive investment in counter-drone systems. Money spent on conventional manned weapons systems increasingly looks to be as wasted as spending on the cavalry in the 1930s.
The Atlantic makes similar points.
There’s a balance between the cost of the thing, and the cost to destroy the thing, and that balance is changing dramatically. This isn’t new, of course. Here’s an article from last year about the cost of drones versus the cost of top-of-the-line fighter jets. If $35K in drones (117 drones times an estimated $300 per drone) can destroy $7B in Russian bombers and other long-range aircraft, why would anyone build more of those planes? And we can have this discussion about ships, or tanks, or pretty much every other military vehicle. And then we can add in drone-coordinating technologies like swarming.
Clearly we need more research on remotely and automatically disabling drones.
Rapid7 Q1 2025 Incident Response Findings
Post Syndicated from Chris Boyd original https://blog.rapid7.com/2025/06/04/rapid7-q1-2025-incident-response-findings/

Rapid7’s Q1 2025 incident response data highlights several key initial access vector (IAV) trends, shares salient examples of incidents investigated by the Rapid7 Incident Response (IR) team, and digs into threat data by industry as well as some of the more commonly seen pieces of malware appearing in incident logs.
Is having no MFA solution in place still one of the most appealing vulnerabilities for threat actors? Will you see the same assortment of malware regardless of whether you work in business services or media and communications? And how big a problem could one search engine query possibly be, anyway?
The answer to that last question is “very,” as it turns out. As for the rest…
Initial access vectors
Below, we highlight the key movers and shakers for IAVs across cases investigated by Rapid7’s IR team. While you’ll notice a fairly even split among several vectors such as exposed remote desktop protocol (RDP) services and SEO poisoning, one in particular is clearly the leader of the pack where compromising organizations is concerned: stolen credentials to valid/active accounts with no multi-factor authentication (MFA) enabled.

Valid account credentials — with no MFA in place to protect the organization should they be misused — are still far and away the biggest stumbling block for organizations investigated by the Rapid7 IR team, occurring in 56% of all incidents this first quarter.
Exposed RDP services accounted for 6% of incidents as the IAV, yet they were abused by attackers more generally in 44% of incidents. This tells us that third parties remain an important consideration in an organization’s security hygiene.
Valid accounts / no MFA: Top of the class
Rapid7 regularly bangs the drum for tighter controls where valid accounts and MFA are concerned. As per the key findings, 56% of all incidents in Q1 2025 involved valid accounts / no MFA as the initial access vector. In fact, there’s been very little change since Q3 2024, and as good as no difference between the last two quarters:

Vulnerability exploitation: Cracks in the armor
Rapid7’s IR services team observed several vulnerabilities used, or likely to have been used, as an IAV in Q1 2025. CVE-2024-55591 for example, the IAV for an incident in manufacturing, is a websocket-based race condition authentication bypass affecting Fortinet’s FortiOS and FortiProxy flagship appliances. Successful exploitation results in the ability to execute arbitrary CLI console commands as the super_admin user. The CVE-2024-55591 advisory was published at the beginning of 2025, and it saw widespread exploitation in the wild.
One investigation revealed attackers using the above flaw to exploit vulnerable firewall devices and create local and administrator accounts with legitimate-looking names (e.g., references to “Admin”, “I.T.”, “Support”). This allowed access to firewall dashboards, which may have contained useful information about the devices’ users, configurations, and network traffic. Policies were created which allowed for leveraging of remote VPN services, and the almost month-long dwell time observed in similar incidents may suggest initial access broker (IAB) activity, or a possible intended progression to data exfiltration and ransomware.
Exposed RMM tooling: A path to ransomware
As noted above, 6% of IAV incidents were a result of exposed remote monitoring and management (RMM) tooling. RMMs, used to remotely manage and access devices, are often used to gain initial access, or form part of the attack chain leading to ransomware.
One investigation revealed a version of SimpleHelp vulnerable to several critical privilege escalation and remote code execution vulnerabilities, which included CVE-2024-57726, CVE-2024-57727, and CVE-2024-57728.
These CVEs target the SimpleHelp remote access solution. Exploiting CVE-2024-57727 permits an unauthenticated attacker to leak SimpleHelp “technician” password hashes. If one is cracked, the attacker can log-in as a remote-access technician. Lastly, the attacker can exploit CVE-2024-57726 and CVE-2024-57728 to elevate to SimpleHelp administrator and trigger remote code execution, respectively. CVE-2024-57727 was added to CISA KEV in February 2025.
The vulnerable RMM solution was used to gain initial access and threat actors used PowerShell to create Windows Defender exclusions, with the ultimate goal of deploying INC Ransomware on target systems.
SEO poisoning: When a quick search leads to disaster
SEO poisoning, once the scourge of search engines everywhere, may not be high on your list of priorities. However, it still has the potential to wreak havoc on a network. Here, the issue isn’t so much rogue entries in regular search results, but instead the paid sponsored ads directly above typical searches. Note how many sponsored results sit above the genuine site related to this incident:

This investigation revealed a tale of two search results, where one led to a genuine download of a tool designed to monitor virtual environments, and the other led to malware. When faced with both options, a split-second decision went with the latter and what followed was an escalating series of intrusion, data exfiltration and—eventually—ransomware.

On the same day of initial compromise, the attacker moved laterally using compromised credentials via RDP, installing several RMM tools such as AnyDesk and SplashTop. It is likely that the threat actor searched for insecurely stored password files and targeted password managers. They also attempted to modify and/or disable various security tools in order to evade detection, and create a local account to enable persistence and avoid domain-wide password resets.
An unauthorized version of WinSCP was used to exfiltrate a few hundred GB of sensitive company data from several systems, and with this mission accomplished only a few tasks remained. The first: attempting to inhibit system recovery by tampering with the Volume Shadow Copy Service (VSS), clearing event logs, deleting files, and also attempting to target primary backups for data destruction. The second: deployment of Qilin ransomware and a blackmail note instructing the victim to communicate via a TOR link lest the data be published to their leak site.
Qilin ranked 7 in our top ransomware groups of Q1 2025 for leak post frequency, racking up 111 posts from January through March. Known for double-extortion attacks across healthcare, manufacturing, and financial sectors, Qilin (who, despite their name, are known not to be Chinese speakers, but rather Russian-speaking) has also recently been seen deployed by North Korean threat actors Moonstone Sleet.
Attacker behavior observations
Bunnies everywhere: Tracking a top malware threat
BunnyLoader, the Malware as a Service (MaaS) loader possessing a wealth of capabilities including clipboard and credential theft, keylogging, and the ability to deploy additional malware, is one of the most prolific presences Rapid7 has seen this first quarter of 2025. In many cases, it’s also daisy-chained to many of the other payloads and tactics which make repeated appearances.
To really drive this message home: BunnyLoader is the most observed payload across almost every industry we focused on. Whether we’re talking manufacturing, healthcare, business services or finance, it’s typically well ahead of the rest of the pack. Here are our findings across the 5 most targeted industries of Q1:

BunnyLoader is in pole position not only for the 5 industries shown above, but across 12 of 13 industries overall, with 40% of all incidents observed involving this oft-updated malware.
Just over half of that 40% total involved a fake CAPTCHA (commonly used for the purpose of victims executing malicious code), with malicious / compromised sites appearing in a quarter of BunnyLoader cases. Rogue documents, which may be booby-trapped with malware or pave the way for potential phishing attacks, bring up the rear at just 9% of all BunnyLoader appearances recorded. First offered for sale in 2023 for a lifetime-use cost of $250, its continued development and large range of features make it an attractive proposition for rogues operating on a budget.
Targeted organizations: The manufacturing magnet
Manufacturing organizations were targeted in more than 24% of incidents the Rapid7 IR team observed, by far the most targeted industry in Q1 based on both Rapid7’s ransomware analytics and IR team observations. The chart below compares Rapid7’s industry-wide data (comprising a wide range of payloads and tactics) with ransomware leak post specific data. In both cases, manufacturing is a fair way ahead of other industries; this reflects its status as one of the most popular targets for ransomware groups over the last couple of years.
The manufacturing industry is an attack vector for nation states because it is an important component of global trade. It is also an area that has many legacy and older, operational technologies (OT). Combine unpatched legacy systems with complicated supply chains, and you have a risk that nation state actors will find an attractive target. This is especially the case when considering that many manufacturing organizations have critical contracts with governments, and attacks can cause severe disruption if they’re not speedily resolved.

Conclusion
Q1 2025 resembles a refinement of successful tactics, as opposed to brand new innovations brought to the table. Our Q1 ransomware analytics showed threat actors making streamlined tweaks to a well-oiled machine, and we find many of the same “evolution, not revolution” patterns occurring here.
This progression is particularly applicable in the case of initial access via valid accounts with no MFA protection. We expect to see no drop in popularity while businesses continue to leave easy inroads open and available to skilled (and unskilled) attackers.
In addition, the risk of severe compromise stemming from seemingly harmless online searches underscores the necessity for organizations to reexamine basic security best practices, alongside deploying robust detection and response capabilities. Businesses addressing these key areas for concern will be better equipped to defend against what should not be an inevitable slide into data exfiltration and malware deployment.
Broadcom Tomahawk 6 Launched for 1.6TbE Generation
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/broadcom-tomahawk-6-launched-for-1-6tbe-generation/
Today Broadcom is launching its next-generation of switch ASICs with the Broadcom Tomahawk 6 series. This is a new 102.4Tbps switch that can handle up to 64 ports of 1.6TbE. Yes, we are now replacing the “Gigabit” with the “Terabit” Ethernet port era. The two new ASICs, the Broadcom BCM78910 and BCM78914 offer two different […]
The post Broadcom Tomahawk 6 Launched for 1.6TbE Generation appeared first on ServeTheHome.
Why kids still need to learn to code in the age of AI
Post Syndicated from Philip Colligan original https://www.raspberrypi.org/blog/why-kids-still-need-to-learn-to-code-in-the-age-of-ai/
Today we’re publishing a position paper setting out five arguments for why we think that kids still need to learn to code in the age of artificial intelligence.
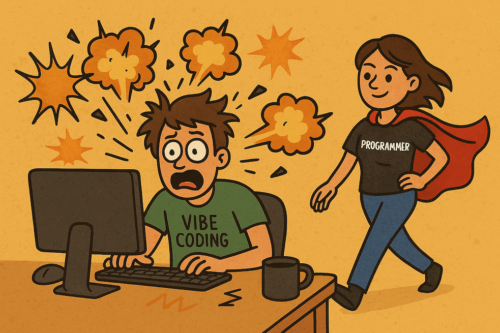
Just like every wave of technological innovation that has come before, the advances in artificial intelligence (AI) are raising profound questions about the future of human work. History teaches us that technology has the potential to both automate and augment human effort, destroying some jobs and creating new ones. The only thing we know for sure is that it is impossible to predict the precise nature and pace of the changes that are coming.
One of the fastest-moving applications of generative AI technologies are the systems that can generate code. What started as the coding equivalent of autocomplete has quickly progressed to tools that can generate increasingly complex code from natural language prompts.
This has given birth to the notion of “vibe-coding” and led some commentators to predict the end of the software development industry as we know it. It shouldn’t be a surprise then that there is a vigorous debate about whether kids still need to learn to code.
In the position paper we put forward five arguments for why we think the answer is an unequivocal yes.
We need humans who are skilled programmers
First, we argue that even in a world where AI can generate code, we need skilled human programmers who can think critically, solve problems, and make ethical decisions. The large language models that underpin these tools are probabilistic systems designed to provide statistically acceptable outputs and, as any skilled software engineer will tell you, simply writing more code faster isn’t necessarily a good thing.
Learning to code is an essential part of learning to program
Learning to code is the most effective way we know for a young person to develop the mental models and fluency to become a skilled human programmer. The hard cognitive work of reading, modifying, writing, explaining, and testing code is precisely how young people develop a deep understanding of programming and computational thinking.
Learning to code will open up even more opportunities in the age of AI
While there’s no doubt that AI is going to reshape the labour market, the evidence from history suggests that it will increase the reach of programming and computational approaches across the economy and into new domains, creating demand for humans who are skilled programmers. We also argue that coding is no longer just for software engineers, it’s becoming a core skill that enables people to work effectively and think critically in a world shaped by intelligent machines. From healthcare to agriculture, we are already seeing demand for people who can combine programming with domain-specific skills and craft knowledge.
Coding is a literacy that helps young people have agency in a digital world
Alongside the arguments for coding as a route to opening up economic opportunities, we argue that coding and programming gives young people a way to express themselves, to learn, and to make sense of the world.
And perhaps most importantly, that learning to code is about power. Providing young people with a solid grounding in computational literacy, developed through coding, helps ensure that they have agency. Without it, they risk being manipulated by systems they don’t understand. As Rushkoff said: “Program, or be programmed”.
The kids who learn to code will shape the future
Finally, we argue that the power to create with technology is already concentrated in too small and homogenous a group of people. We need to open up the opportunity to learn to code to all young people because it will help us mobilise the full potential of human talent, will lead to more inclusive and effective digital solutions to the big global challenges we face, and will help ensure that everyone can share in the societal and economic benefits of technological progress.
The work we need to do
We end the paper with a call to action for all of us working in education. We need to challenge the false narrative that AI is removing the need for kids to learn to code, and redouble our efforts to ensure that all young people are equipped to take advantage of the opportunities in a world where AI is ubiquitous.
You can read the full paper here:
The cartoon image for this blog was created using ChatGPT-4o, which was prompted to produce a “whimsical cartoon that expresses some of the key ideas in the position paper”. It took several iterations.
The post Why kids still need to learn to code in the age of AI appeared first on Raspberry Pi Foundation.
The Great Flood of 1921
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=NO8hMM6u3bQ
Comic for 2025.06.04 – Burning
Post Syndicated from Explosm.net original https://explosm.net/comics/burning
New Cyanide and Happiness Comic
How We Reduced the Impact of Zombie Clients
Post Syndicated from Let's Encrypt original https://letsencrypt.org/2025/06/04/how-we-reduced-the-impact-of-zombie-clients.html
Every night, right around midnight (mainly UTC), a horde of zombies wakes up and clamors for … digital certificates!
The zombies in question are abandoned or misconfigured Internet servers and ACME clients that have been set to request certificates from Let’s Encrypt. As our certificates last for at most 90 days, these zombie clients’ software knows that their certificates are out-of-date and need to be replaced. What they don’t realize is that their quest for new certificates is doomed! These devices are cursed to seek certificates again and again, never receiving them.
But they do use up a lot of certificate authority resources in the process.
The Zombie Client Problem
Unlike a human being, software doesn’t give up in frustration, or try to modify its approach, when it repeatedly fails at the same task. Our emphasis on automation means that the vast majority of Let’s Encrypt certificate renewals are performed by automated software. This is great when those renewals succeed, but it also means that forgotten clients and devices can continue requesting renewals unsuccessfully for months, or even years.
How might that happen? Most often, it happens when a device no longer has a domain name pointed to it. The device itself doesn’t know that this has changed, so it treats renewal failures as transient even though they are actually permanent. For instance:
- An organization may have allowed a domain name registration to lapse because it is no longer needed, but its servers are still configured to request certs for it.
- Or, a home user stopped using a particular dynamic-DNS domain with a network-attached storage device, but is still using that device at home. The device doesn’t realize that the user no longer expects to use the name, so it keeps requesting certs for it.
- Or, a web hosting or CDN customer migrated to a different service provider, but never informed the old service provider. The old service provider’s servers keep requesting certs unsuccessfully. If the customer was in a free service tier, there might not be invoices or charges reminding the customer to cancel the service.
- Or any number of other, subtler changes in a subscriber’s infrastructure, such as changing a firewall rule or some webserver configuration.
At the scale of Let’s Encrypt, which now covers hundreds of millions of names, scenarios like these have become common, and their impact has become substantial. In 2024, we noticed that about half of all certificate requests to the Let’s Encrypt ACME API came from about a million accounts that never successfully complete any validations. Many of these had completed validations and issued certificates sometime in the past, but nowadays every single one of their validation attempts fails, and they show no signs that this will change anytime soon.
Unfortunately, trying to validate those futile requests still uses resources. Our CA software has to generate challenges, reach out and attempt to validate them over the Internet, detect and report failures, and record all of the associated information in our databases and audit logs. And over time, we’ve seen more and more recurring failures: accounts that always fail their issuance requests have been growing at around 18% per year.
In January, we mentioned that we had been addressing the zombie client problem through our rate limit system. This post provides more detail on that progress.
Our Rate Limit Philosophy
If you’ve used Let’s Encrypt as a subscriber, you may have run into one of our rate limits at some point, maybe during your initial setup process. We have eight different kinds of rate limits in place now; as our January post describes, they’ve become more algorithmically sophisticated and grown to address a wider range of problems. A key principle for Let’s Encrypt is that our rate limiting is not a punishment. We don’t think of rate limits as a way of retaliating against a client for misbehavior. Rate limits are simply a tool to maximize the efficient use of our limited resources and prevent people and programs from using up those resources for no constructive purpose.
We’ve consistently tried to design our rate limit mechanisms in line with that philosophy. So if a misconfiguration or misunderstanding has caused excessive requests in the past, we’re still happy to welcome the user in question back and start issuing them certificates again—once the problem has been addressed. We want the rate limits to put a brake on wasteful use of our systems, but not to frustrate users who are actively trying to make Let’s Encrypt work for them.
In addition, we’ve always implemented our rate limits to err on the side of permissiveness. For example, if the Redis instances where rate limits are tracked have an outage or lose data, the system is designed to permit more issuance rather than less issuance as a result.
We wanted to create additional limits that would target zombie clients, but in a correspondingly non-punitive way that would avoid any disruption to valid issuance, and welcome subscribers back quickly if they happened to notice and fix a long-time problem with their setups.
Our Zombie-Related Rate Limits and Their Impact
In planning a new zombie-specific response, we decided on a “pausing” approach, which can temporarily limit an account’s ability to proceed with certificate requests. The core idea is that, if a particular account consistently fails to complete validation for a particular hostname, we’ll pause that account-hostname pair. The pause means that any new order requests from that account for that hostname will be rejected immediately, before we get to the resource-intensive validation phase.
This approach is more finely targeted than pausing an entire account. Pausing account-hostname pairs means that your ability to issue certs for a specific name could be paused due to repeated failures, but you can still get all of your other certs like normal. So a large hosting provider doesn’t have to fear that its certificate issuance on behalf of one customer will be affected by renewal failures related to a problem with a different customer’s domain name. The account-specificity of the pause, in turn, means that validation failures from one subscriber or device won’t prevent a different subscriber or device from attempting to validate the same name, as long as the devices in question don’t share a single Let’s Encrypt account.
In September 2024, we began applying our zombie rate limits manually by pausing about 21,000 of the most recurrently-failing account-hostname pairs, those which were consistently repeating the same failed requests many times per day, every day. After implementing that first round of pauses, we immediately saw a significant impact on our failed request rates. As we announced at that time, we also began using a formula to automatically pause other zombie client account-hostname pairs from December 2024 onward. The associated new rate limit is called “Consecutive Authorization Failures per Hostname Per Account” (and is independent of the existing “Authorization Failures per Hostname Per Account” limit, which resets every hour).
This formula relates to the frequency of successive failed issuance requests for the same domain name by the same Let’s Encrypt account. It applies only to failures that happen again and again, with no successful issuances at all in between: a single successful validation immediately resets the rate limit all the way to zero. Like all of our rate limits, this is not a punitive measure but is simply intended to reduce the waste of resources. So, we decided to set the thresholds rather high in the expectation that we would catch only the most disruptive zombie clients, and ultimately only those clients that were extremely unlikely to succeed in the future based on their substantial history of failed requests. We don’t hurry to block requesters as zombies: according to our current formula, client software following the default established by EFF’s Certbot (two renewal attempts per day) would be paused as a zombie only after about ten years of constant failures. More aggressive failed issuance attempts will get a client paused sooner, but clients will generally have to fail hundreds or thousands of attempts in a row before they are paused.
Most subscribers using mainstream client applications with default configurations will never encounter this rate limit, even if they forget to deactivate renewal attempts for domains that are no longer pointed at their servers. As described below, our current limit is already providing noticeable benefits with minimal disruption, and we’re likely to tighten it a bit in the near future, so it will trigger after somewhat fewer consecutive failures.
Self-Service Unpausing
A key feature in our zombie issuance pausing mechanism is self-service unpausing. Whenever an account-hostname pair is paused, any new certificate requests for that hostname submitted by that account are immediately rejected. But this means that the “one successful validation immediately resets the rate limit counter” feature can no longer come into effect: once they’re paused, they can’t even attempt validation anymore.
So every rejection comes with an error message explaining what has happened and a custom link that can be used to immediately unpause that account-hostname pair and remove any other pauses on the same account at the same time. The point of this is that subscribers who notice at some point that issuance is failing and want to intervene to get it working again have a straightforward option to let Let’s Encrypt know that they’re aware of the recurring failures and are still planning to use a particular account. As soon as subscribers notify us via the self-service link, they’ll be able to issue certificates again.
Currently, the user interface for an affected subscriber looks like this:
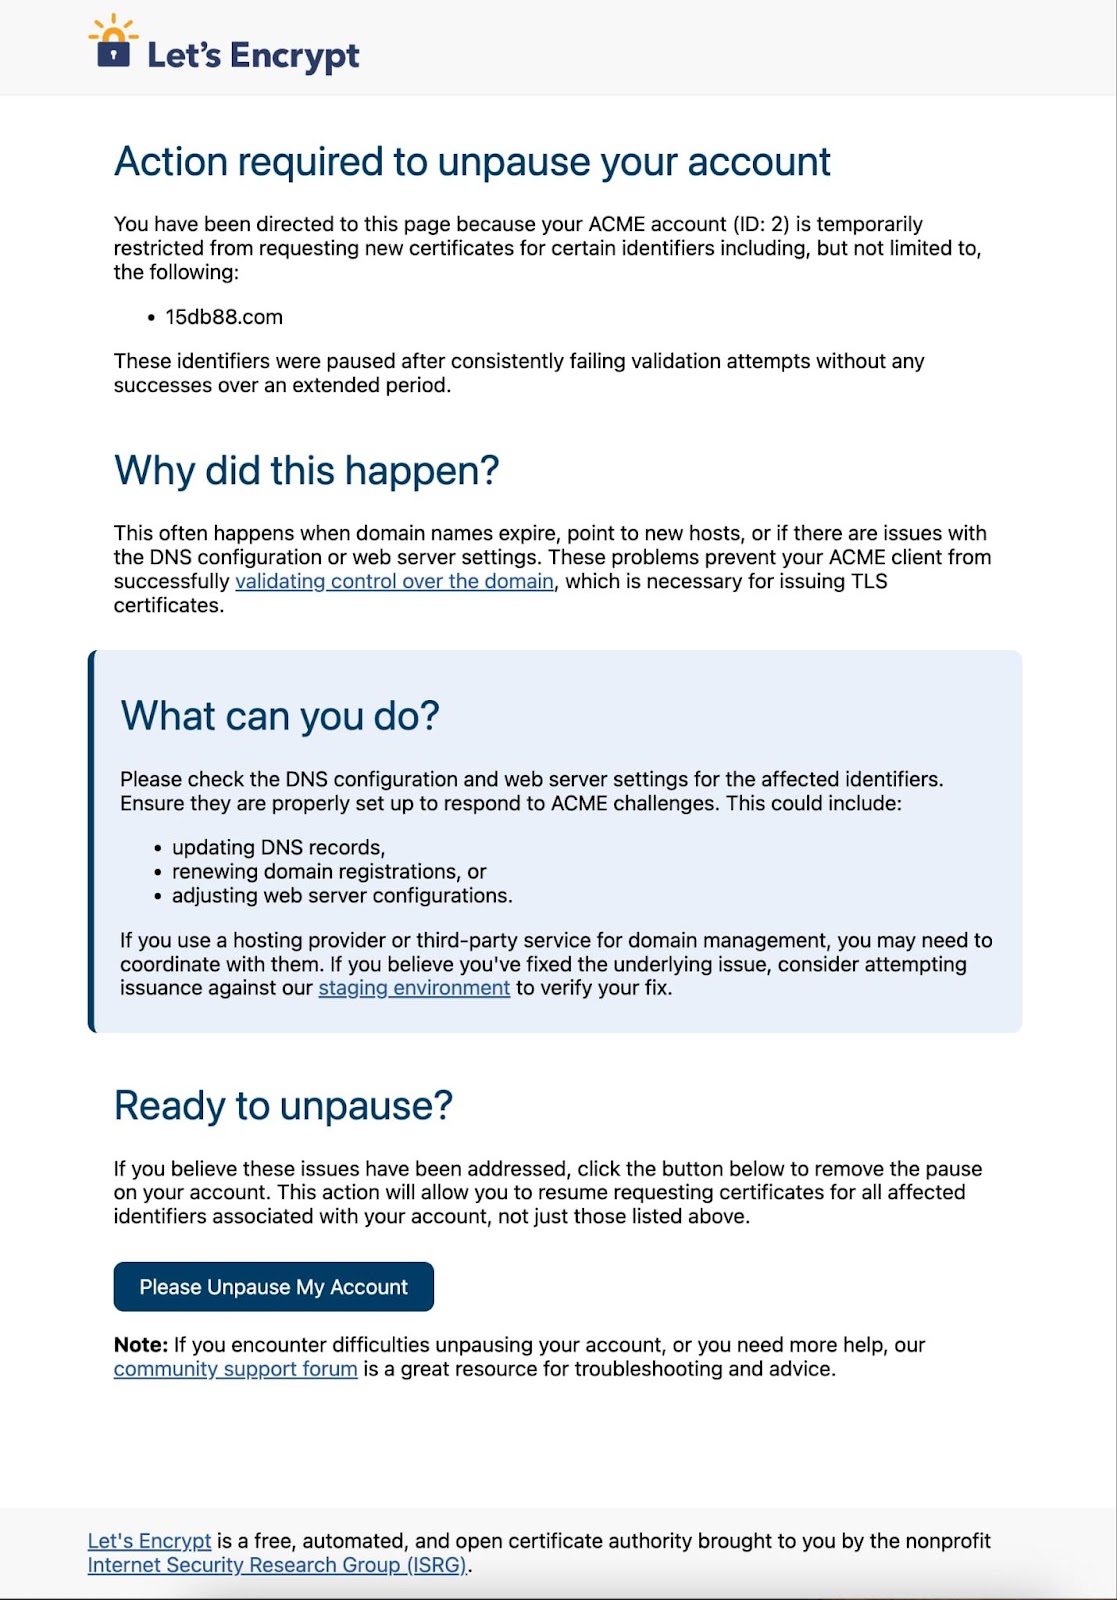
This link would be provided via an ACME error message in response to any request that was blocked due to a pause account-hostname pair.
As it’s turned out, the unpause option shown above has only been used by about 3% of affected accounts! This goes to show that most of the zombies we’ve paused were, in fact, well and truly forgotten about.
However, the unpause feature is there for whenever it’s needed, and there may be cases when it will become more important. A very large integration could trigger the zombie-related rate limits if a newly-introduced software bug causes what looks like a very high volume of zombie requests in a very short time. In that case, once that bug has been noticed and fixed, an integrator may need to unpause its issuance on behalf of lots of customers at once. Our unpause feature permits unpausing 50,000 domain names on a single account at a time, so even the largest integrators can get themselves unpaused expeditiously in this situation.
Conclusion
We’ve been very happy with the results of our zombie mitigation measures, and, as far as we can tell, there’s been almost no impact for subscribers! Our statistics indicate that we’ve managed to reduce the load on our infrastructure while causing no detectable harm or inconvenience to subscribers’ valid issuance requests.
Since implementing the manual pauses in September and the automated pauses in December, we’ve seen:
- Over 100,000 account-hostname pairs have been paused for excessive failures.
- We received zero (!) associated complaints or support requests.
- About 3,200 people manually unpaused issuance.
- Failed certificate orders fell by about 30% so far, and should continue to fall over time as we fine-tune the rate limit formula and catch more zombie clients.
The new rate limit and the self-service unpause system are also ready to deal with circumstances that might produce more zombie clients in the future. For instance, we’ve announced that we’re going to be discontinuing renewal reminder emails soon. If some subscribers overlook failed renewals in the future, we might see more paused clients that result from unintentional renewal failures. We think taking advantage of the existing self-service unpause feature will be straightforward in that case. But it’s much better to notice problems and get them fixed up front, so please remember to set up your own monitoring to avoid unnoticed renewal failures in the future.
If you’re a subscriber who’s had occasion to use the self-service unpause feature, we’d love your feedback on the Community Forum about your experience using the feature and the circumstances that surrounded your account’s getting paused.
Also, if you’re a Let’s Encrypt client developer, please remember to make renewal requests at a random time (not precisely at midnight) so that the load on our infrastructure is smoothed out. You can also reduce the impact of zombie renewals by repeating failed requests somewhat less frequently over time (a “back-off” strategy), especially if the failure reason makes it look like a domain name may no longer be in use at all.
Trojan Horse
Post Syndicated from xkcd.com original https://xkcd.com/3098/
How We Reduced the Impact of Zombie Clients
Post Syndicated from Let's Encrypt original https://letsencrypt.org/2025/06/04/how-we-reduced-the-impact-of-zombie-clients/
Every night, right around midnight (mainly UTC), a horde of zombies wakes up and clamors for … digital certificates!
The zombies in question are abandoned or misconfigured Internet servers and ACME clients that have been set to request certificates from Let’s Encrypt. As our certificates last for at most 90 days, these zombie clients’ software knows that their certificates are out-of-date and need to be replaced. What they don’t realize is that their quest for new certificates is doomed! These devices are cursed to seek certificates again and again, never receiving them.
But they do use up a lot of certificate authority resources in the process.
The Zombie Client Problem
Unlike a human being, software doesn’t give up in frustration, or try to modify its approach, when it repeatedly fails at the same task. Our emphasis on automation means that the vast majority of Let’s Encrypt certificate renewals are performed by automated software. This is great when those renewals succeed, but it also means that forgotten clients and devices can continue requesting renewals unsuccessfully for months, or even years.
How might that happen? Most often, it happens when a device no longer has a domain name pointed to it. The device itself doesn’t know that this has changed, so it treats renewal failures as transient even though they are actually permanent. For instance:
- An organization may have allowed a domain name registration to lapse because it is no longer needed, but its servers are still configured to request certs for it.
- Or, a home user stopped using a particular dynamic-DNS domain with a network-attached storage device, but is still using that device at home. The device doesn’t realize that the user no longer expects to use the name, so it keeps requesting certs for it.
- Or, a web hosting or CDN customer migrated to a different service provider, but never informed the old service provider. The old service provider’s servers keep requesting certs unsuccessfully. If the customer was in a free service tier, there might not be invoices or charges reminding the customer to cancel the service.
- Or any number of other, subtler changes in a subscriber’s infrastructure, such as changing a firewall rule or some webserver configuration.
At the scale of Let’s Encrypt, which now covers hundreds of millions of names, scenarios like these have become common, and their impact has become substantial. In 2024, we noticed that about half of all certificate requests to the Let’s Encrypt ACME API came from about a million accounts that never successfully complete any validations. Many of these had completed validations and issued certificates sometime in the past, but nowadays every single one of their validation attempts fails, and they show no signs that this will change anytime soon.
Unfortunately, trying to validate those futile requests still uses resources. Our CA software has to generate challenges, reach out and attempt to validate them over the Internet, detect and report failures, and record all of the associated information in our databases and audit logs. And over time, we’ve seen more and more recurring failures: accounts that always fail their issuance requests have been growing at around 18% per year.
In January, we mentioned that we had been addressing the zombie client problem through our rate limit system. This post provides more detail on that progress.
Our Rate Limit Philosophy
If you’ve used Let’s Encrypt as a subscriber, you may have run into one of our rate limits at some point, maybe during your initial setup process. We have eight different kinds of rate limits in place now; as our January post describes, they’ve become more algorithmically sophisticated and grown to address a wider range of problems. A key principle for Let’s Encrypt is that our rate limiting is not a punishment. We don’t think of rate limits as a way of retaliating against a client for misbehavior. Rate limits are simply a tool to maximize the efficient use of our limited resources and prevent people and programs from using up those resources for no constructive purpose.
We’ve consistently tried to design our rate limit mechanisms in line with that philosophy. So if a misconfiguration or misunderstanding has caused excessive requests in the past, we’re still happy to welcome the user in question back and start issuing them certificates again—once the problem has been addressed. We want the rate limits to put a brake on wasteful use of our systems, but not to frustrate users who are actively trying to make Let’s Encrypt work for them.
In addition, we’ve always implemented our rate limits to err on the side of permissiveness. For example, if the Redis instances where rate limits are tracked have an outage or lose data, the system is designed to permit more issuance rather than less issuance as a result.
We wanted to create additional limits that would target zombie clients, but in a correspondingly non-punitive way that would avoid any disruption to valid issuance, and welcome subscribers back quickly if they happened to notice and fix a long-time problem with their setups.
Our Zombie-Related Rate Limits and Their Impact
In planning a new zombie-specific response, we decided on a “pausing” approach, which can temporarily limit an account’s ability to proceed with certificate requests. The core idea is that, if a particular account consistently fails to complete validation for a particular hostname, we’ll pause that account-hostname pair. The pause means that any new order requests from that account for that hostname will be rejected immediately, before we get to the resource-intensive validation phase.
This approach is more finely targeted than pausing an entire account. Pausing account-hostname pairs means that your ability to issue certs for a specific name could be paused due to repeated failures, but you can still get all of your other certs like normal. So a large hosting provider doesn’t have to fear that its certificate issuance on behalf of one customer will be affected by renewal failures related to a problem with a different customer’s domain name. The account-specificity of the pause, in turn, means that validation failures from one subscriber or device won’t prevent a different subscriber or device from attempting to validate the same name, as long as the devices in question don’t share a single Let’s Encrypt account.
In September 2024, we began applying our zombie rate limits manually by pausing about 21,000 of the most recurrently-failing account-hostname pairs, those which were consistently repeating the same failed requests many times per day, every day. After implementing that first round of pauses, we immediately saw a significant impact on our failed request rates. As we announced at that time, we also began using a formula to automatically pause other zombie client account-hostname pairs from December 2024 onward. The associated new rate limit is called “Consecutive Authorization Failures per Hostname Per Account” (and is independent of the existing “Authorization Failures per Hostname Per Account” limit, which resets every hour).
This formula relates to the frequency of successive failed issuance requests for the same domain name by the same Let’s Encrypt account. It applies only to failures that happen again and again, with no successful issuances at all in between: a single successful validation immediately resets the rate limit all the way to zero. Like all of our rate limits, this is not a punitive measure but is simply intended to reduce the waste of resources. So, we decided to set the thresholds rather high in the expectation that we would catch only the most disruptive zombie clients, and ultimately only those clients that were extremely unlikely to succeed in the future based on their substantial history of failed requests. We don’t hurry to block requesters as zombies: according to our current formula, client software following the default established by EFF’s Certbot (two renewal attempts per day) would be paused as a zombie only after about ten years of constant failures. More aggressive failed issuance attempts will get a client paused sooner, but clients will generally have to fail hundreds or thousands of attempts in a row before they are paused.
Most subscribers using mainstream client applications with default configurations will never encounter this rate limit, even if they forget to deactivate renewal attempts for domains that are no longer pointed at their servers. As described below, our current limit is already providing noticeable benefits with minimal disruption, and we’re likely to tighten it a bit in the near future, so it will trigger after somewhat fewer consecutive failures.
Self-Service Unpausing
A key feature in our zombie issuance pausing mechanism is self-service unpausing. Whenever an account-hostname pair is paused, any new certificate requests for that hostname submitted by that account are immediately rejected. But this means that the “one successful validation immediately resets the rate limit counter” feature can no longer come into effect: once they’re paused, they can’t even attempt validation anymore.
So every rejection comes with an error message explaining what has happened and a custom link that can be used to immediately unpause that account-hostname pair and remove any other pauses on the same account at the same time. The point of this is that subscribers who notice at some point that issuance is failing and want to intervene to get it working again have a straightforward option to let Let’s Encrypt know that they’re aware of the recurring failures and are still planning to use a particular account. As soon as subscribers notify us via the self-service link, they’ll be able to issue certificates again.
Currently, the user interface for an affected subscriber looks like this:
This link would be provided via an ACME error message in response to any request that was blocked due to a pause account-hostname pair.
As it’s turned out, the unpause option shown above has only been used by about 3% of affected accounts! This goes to show that most of the zombies we’ve paused were, in fact, well and truly forgotten about.
However, the unpause feature is there for whenever it’s needed, and there may be cases when it will become more important. A very large integration could trigger the zombie-related rate limits if a newly-introduced software bug causes what looks like a very high volume of zombie requests in a very short time. In that case, once that bug has been noticed and fixed, an integrator may need to unpause its issuance on behalf of lots of customers at once. Our unpause feature permits unpausing 50,000 domain names on a single account at a time, so even the largest integrators can get themselves unpaused expeditiously in this situation.
Conclusion
We’ve been very happy with the results of our zombie mitigation measures, and, as far as we can tell, there’s been almost no impact for subscribers! Our statistics indicate that we’ve managed to reduce the load on our infrastructure while causing no detectable harm or inconvenience to subscribers’ valid issuance requests.
Since implementing the manual pauses in September and the automated pauses in December, we’ve seen:
- Over 100,000 account-hostname pairs have been paused for excessive failures.
- We received zero (!) associated complaints or support requests.
- About 3,200 people manually unpaused issuance.
- Failed certificate orders fell by about 30% so far, and should continue to fall over time as we fine-tune the rate limit formula and catch more zombie clients.
The new rate limit and the self-service unpause system are also ready to deal with circumstances that might produce more zombie clients in the future. For instance, we’ve announced that we’re going to be discontinuing renewal reminder emails soon. If some subscribers overlook failed renewals in the future, we might see more paused clients that result from unintentional renewal failures. We think taking advantage of the existing self-service unpause feature will be straightforward in that case. But it’s much better to notice problems and get them fixed up front, so please remember to set up your own monitoring to avoid unnoticed renewal failures in the future.
If you’re a subscriber who’s had occasion to use the self-service unpause feature, we’d love your feedback on the Community Forum about your experience using the feature and the circumstances that surrounded your account’s getting paused.
Also, if you’re a Let’s Encrypt client developer, please remember to make renewal requests at a random time (not precisely at midnight) so that the load on our infrastructure is smoothed out. You can also reduce the impact of zombie renewals by repeating failed requests somewhat less frequently over time (a “back-off” strategy), especially if the failure reason makes it look like a domain name may no longer be in use at all.
HyperBowl: From Sony Arcade to Windows XP Classic! An LGR Retrospective
Post Syndicated from LGR original https://www.youtube.com/watch?v=i3-3dvgYt7c
Marty Baron on Congress and the press since Watergate
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=OFbdcP7K3OU
Introducing managed query results for Amazon Athena
Post Syndicated from Guy Bachar original https://aws.amazon.com/blogs/big-data/introducing-managed-query-results-for-amazon-athena/
Amazon Athena makes it simple to analyze data without having to set up and manage data processing infrastructure. However, traditionally, you needed to set up an Amazon Simple Storage Service (Amazon S3) bucket to store query results before they could run queries with Athena. The need arose to make it even simpler to start using Athena, with fewer setup steps.
That’s why we’re thrilled to introduce managed query results, a new Athena feature that automatically stores, secures, and manages the lifecycle of query result data for you at no additional cost. Managed query results simplifies your user experience by removing the need to create or choose an S3 bucket in your account to hold results before you run queries. It helps reduce your monthly cost by shifting temporary storage of query results from your S3 bucket to Athena, and eliminates the need for separate processes to delete query result data from your S3 bucket after it’s no longer needed. Now, Athena offers both service managed, temporary result storage and customer managed Amazon S3 storage options to meet different needs.
What’s more, using managed query results doesn’t require complex changes to applications that read query results from existing Athena interfaces, and increases data security. Access to managed query result data is now associated with AWS Identity and Access Management (IAM) permissions scoped to individual Athena workgroups, instead of S3 buckets. Additionally, you can automatically encrypt result data with AWS Key Management Service (AWS KMS) using AWS owned or customer managed keys.
In this post, we demonstrate how to get started with managed query results and, by removing the undifferentiated effort spent on query result management, how Athena helps you get insights from your data in fewer steps than before.
Solution overview
When you use managed query results, you no longer need to create and choose S3 buckets to store query results, or manage lifecycle rules to make sure the result data is eventually cleaned up. The following are some scenarios where this is beneficial:
- Financial analysts working in teams analyzing market data, each covering different investment areas or financial instruments, might use different workgroups for different kinds of analyses or projects. Now, analysts don’t need to spend time setting up S3 buckets or worry about cleaning up query results when their work is done.
- Compliance teams can run audit queries on transaction data for regulatory reporting while making sure only authorized team members can access sensitive query results through IAM permissions. Because query results are cleaned up automatically, the compliance team no longer requires separate processes to delete query result data.
- Data and analytics and platform automation teams who are responsible for streamlined onboarding of new users and teams no longer need to configure individual S3 buckets and permissions for different users and teams, simplifying their automation code.
The following are some of the key features of managed query results in Athena:
- It removes the need to choose an S3 bucket location before you run queries.
- There is no additional cost to store your query results, and query results are automatically deleted after a period of time, reducing management overhead from separate bucket cleanup processes.
- It’s straightforward to get started: new and preexisting workgroups can be seamlessly configured to use managed query results. You can have a mix of Athena managed and customer managed query results in your AWS account.
- You can use streamlined IAM permissions with access to read results using
GetQueryResultsandGetQueryResultsStreamtied to individual workgroups. - Query results are automatically encrypted with your choice of AWS owned or customer managed KMS keys.
Let’s walk through how to get started with managed query results.
Configure your workgroup
Complete the following steps to configure your workgroup:
- On the Athena console, choose Workgroups in the navigation pane.
- Choose Create workgroup.
Alternatively, you can select an existing workgroup and choose Edit.
- For Query result configuration, select Athena managed.
- Navigate to the Athena console. To create a new workgroup, in the Workgroups page select the Create Workgroup button. To edit an existing workgroup, select a workgroup from the list and in the workgroup detail page, select the Edit button. Under Query result configuration section, you will see the option for Athena managed:
- For Encrypt query results, choose your preferred encryption method

Figure 1: Query result configuration
Step 2: Configure Encryption
Choose your preferred encryption method for query results:
-
- Encrypt using an AWS owned key – This is the default option. It indicates that you want query results to be encrypted and decrypted by an AWS owned key.
- Encrypt using a customer managed key – Choose this option if you want to encrypt and decrypt query results with your own key. To have Athena use your customer managed key, specify the Athena service in the
Principalelements of the key policy. For more information, see Setup an AWS KMS key policy for managed storage. To run queries, the user querying data needs permission to access your key.
Query your data
After you’ve configured your workgroup for managed query results, you can immediately start running queries. Let’s run a sample query against the AWS Cost and Usage Report.
The Athena console banner indicates that our workgroup, demo-workgroup, was updated to use managed query results. Our query ran successfully, and we didn’t need to set up an S3 bucket. To download these results, choose Download results CSV.

Figure 2: Running a query against the Cost and Usage report in the Athena console
You can access these results through the Athena console and using the Athena APIs.

Figure 3: Accessing the query results via the Athena API
Conclusion
In this post, we introduced managed query results, a new Athena feature that streamlines the query experience through automated storage of query results, provides automatic cleanup, and limits query result access with IAM permissions. Managed query results reduces operational overhead, empowering both data analysts running interactive queries and teams building complex analytics pipelines to focus on deriving insights rather than managing infrastructure. We demonstrated how to configure workgroups for managed storage and effectively use this feature in query scenarios.
To start using managed query results with Athena, simply configure your workgroups through the Athena console or APIs. For more information, see Managed query results.
About the Authors
 Guy Bachar is a Sr. Solutions Architect at AWS. He specializes in assisting capital markets and FinTech customers with their cloud transformation journeys. His expertise encompasses identity management, security, and unified communication.
 Sayan Chakraborty is a Sr. Solutions Architect at AWS. He helps large enterprises build secure, scalable, and performant solutions on AWS. With a background in enterprise and technology architecture, he has experience delivering large-scale digital transformation programs across a wide range of industry verticals.
 Darshit Thakkar is a Technical Product Manager at AWS and works out of Boston, Massachusetts. He works closely with customers to understand how they use data, and drives product innovations that make data more actionable at scale.
Why Pilots Don’t Get Therapy
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=cdGxBI9sdbU
How to Age Up on a Warming Planet
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=bsbXDEj6r_0
Dynamically routing requests with Amazon API Gateway routing rules
Post Syndicated from Anton Aleksandrov original https://aws.amazon.com/blogs/compute/dynamically-routing-requests-with-amazon-api-gateway-routing-rules/
Effective API management and routing capabilities are crucial for organizations managing complex application architectures. Whether you’re a technology company rolling out new API versions to millions of users, or a financial services organization conducting A/B tests to optimize customer experiences, the ability to route API traffic dynamically and efficiently is essential.
Today, Amazon API Gateway announces support for dynamic routing rules for custom domain names in all supported AWS Regions. This new capability enables you to route API requests based on HTTP header values, either independently or in combination with URL paths. In this post, you will learn how to use this new capability to implement routing strategies such as API versioning and gradual rollouts without modifying your API endpoints.
Dynamic Routing Rules Overview
Many organizations require dynamic API routing capabilities to support their evolving business needs. As a line-of-business persona, you want to be able to test new user experiences with specific customer segments, while maintaining their existing flows intact. As an engineer, you want to be able to maintain multiple API versions across different client applications while ensuring regulatory compliance. Prior to this launch, developers using API Gateway implemented dynamic routing by using different URL paths, such as “/v1/products” and “/v2/products”.
With this new launch, you can implement dynamic routing logic with a simple declarative configuration within the custom domain name settings. The new routing rule mechanism allows you to make routing decisions based on HTTP headers, base paths, or a combination of both. Developers are no longer required to create new or alter existing paths to smoothly transition between API versions, they can simply specify the desired value in the request HTTP header. Among other possibilities, you can implement cell-based architecture routing, A/B testing, or dynamic backend selection based on hostname, tenant ID, accepted response media type, or cookie value. By implementing routing logic directly within the API Gateway, you can eliminate proxy layers and complex URL structures while maintaining fine-grained control over your API traffic. This new feature seamlessly integrates with existing API Gateway capabilities and supports both public and private REST APIs. The following diagram shows how you can use routing rules for header and base-path based routing. This example uses a single level resource /products to show path matching, however depending on your use-case you could also use multi-level paths like /products/items.

Figure 1. Using routing rules for header and base-path based routing
In the following section you’ll learn how to implement header-based routing, use the new routing rules construct for common scenarios like API versioning and A/B testing, and configure rules with different routing conditions and priorities to achieve the desired behavior.
What is a routing rule
A routing rule is a new resource type uniquely associated with a single custom domain. It represents a collection of conditions that, when matched, cause the incoming request to be forwarded to a specific API and stage. Routing rules have three configuration properties:
- The Conditions property defines the criteria that must be met for actions to be taken. A rule can include up to two header conditions and one base path condition, and all specified conditions must be met to trigger the action. If no conditions are defined for a rule, it serves as a catch-all rule matching all requests.
- The Actions property defines what actions will be taken when rule conditions are met. At the time of this launch the supported action is invoking any stage of any REST API within the same account and region boundaries.
- The Priority property defines the order that rules are evaluated in, with 1 being highest priority and 1,000,000 the lowest. You cannot reuse same priority value for more than one rule. AWS recommends you leave ample space between sequential rules to make it easy to add new rules in future, for example use 100, 200, 300 instead of 1, 2, 3.
Header conditions, specified via a MatchHeaders property, are used to match HTTP request header values, such as x-version=v1. Conforming to RFC 7230, header names are not case sensitive, while header values are. You can also use wildcards in header values for prefix, suffix, and contains match. See the following examples using AWS CloudFormation templates:
Exact match:
Will only match x-version=alpha-v2-latest
Prefix match:
Matches x-version=alpha-v2-latest, but not x-version=alpha-v2
Suffix match:
Will match x-version=alpha-v2-latest and x-version=alpha-v1, but not x-version=beta-v1
Prefix and suffix match.
Matches x-version=alpha-v2-latest and x-version=beta-v2-test, but not x-version=alpha-v1
Base path condition, specified via MatchBasePaths property, is used to match the incoming request path. The matching is case sensitive.
You can have up to two MatchHeaders and one MatchBasePaths conditions per routing rule. Conditions are evaluated using the AND operator, meaning all conditions must be met for the action to be taken. Both condition types support a single comparison value under AnyOf property. The following snippet illustrates a sample routing rule with two MatchHeaders conditions and a single MatchBasePaths condition.
This rule matches requests to https://example.com/products when both header conditions are met – x-version=v2 and x-user-cohort=beta-testers. This rule does not match requests to any other base path, such as https://example.com/orders, or requests that do not match at least one header condition.
For scenarios like API versioning, you can create rules that evaluate headers such as “accept” or “version” to route traffic to different API implementations. For example, to route requests containing “x-version: api-beta” to your beta API, you would create a rule specifying this header condition and set the action to route to your beta API deployment.
Header-based routing also simplifies A/B testing by allowing you to define client cohorts based on custom headers, allowing controlled experiments with different configurations. You can create rules that check for a custom header like “x-test-group” to route specific users to different API implementations. The priority system ensures predictable routing behavior – when multiple rules match a request, the rule with the lowest priority number (highest precedence) determines the routing. Combining header and path conditions within a single rule enables complex routing scenarios such as version-specific routing for specific API resources instead of the entire API, as illustrated in the following diagram.

Figure 2. A routing configuration with two header and one path conditions in API Gateway Console.
Review the API Gateway documentation for detailed guide on creating routing rules.
Configuring Routing Mode
Before you begin creating routing rules, you must first create at least one API, stage, and a custom domain name. You can configure your custom domain name with the new routing mode setting.
- API mappings only. This is the default mode. When using this mode, you can continue to use base path mappings to route requests to different APIs, and not use Routing Rules at all. This mode maintains the current behavior, where requests are routed based on base path mappings only.
- Routing rules then API mappings. With this mode you can use Routing Rules while continuing to keep base path mappings as a fallback. When you use this mode, the Routing Rules always take precedence, and unmatched requests are evaluated against base path mappings. This mode is useful for gradually transitioning your APIs to Routing Rules.
- Routing rules only. This mode gives you the flexibility to use routing rules only, and not rely on the base paths that you may have previously created on the domain using API mappings. This is the recommended routing mode; it is helpful when you are starting off with a new custom domain or finished transitioning from API mappings to Routing Rules for an existing custom domain.
When switching from one routing mode to another, always test your new configuration in non-production environments first. For example, when switching mode from API mappings only to routing rules only, your traffic will only be routed with routing rules; existing API mappings will no longer take effect.
Onboarding to Header-Based Routing
You can adopt the new Header-Based Routing for your existing API Gateway custom domains with zero-downtime, risk-minimized approach. The first step is to configure your custom domain to use the Routing rules then API mappings mode using the API Gateway console, AWS CLI, or your infrastructure-as-code (IaC) tool. This configuration ensures that while you gradually create Routing Rules, your existing base path mappings continue to function as fallback routes. Since Routing Rules are evaluated before base path mappings, and in the absence of any matching rules, requests automatically fall back to your existing base path mappings, your current API traffic remains unaffected during this transition.
Once you’ve configured the routing mode, you can progressively introduce Routing Rules alongside your existing setup. For example, you might start by creating a rule with a specific test header that routes to a new API version, allowing you to validate the routing behavior with controlled test traffic while production traffic continues flowing through your existing base path mappings. As you gain confidence in the new routing configuration, you can gradually expand your rules, adjust priorities, and optionally migrate away from base path mappings entirely. This incremental approach, combined with API Gateway’s observability capabilities described in the next section, enables you to validate each change and ensure your API consumers experience no disruption during the transition.
Observability
API Gateway provides comprehensive visibility into how your routing rules are processing requests through access logging. Each request now includes additional context variables that help you understand the routing decision process. The $context.customDomain.routingRuleIdMatched variable identifies which rule was matched and applied to the request, while existing variables like $context.domainName, $context.apiId, and $context.stage provide the complete routing context. By analyzing these access logs, you can verify routing behavior, troubleshoot unexpected routes, and gather insights about traffic patterns across different API versions or test variants.
End-to-end example
Consider a real-world scenario where a team needs to gradually migrate users to a new API version, such as an e-commerce platform updating its checkout API from v1 to v2. First, the team creates two different REST APIs – one for each version. Then, they set up a Routing Rule with priority 100 that checks for the header x-version=v2 and routes matching requests to the v2 API. They also create another rule with priority 200 that routes all requests with paths starting with /checkout to v1 API as a fallback.

Figure 3. Gradually transitioning clients from v1 to v2 API.
In the application code they add the x-version header for a small percentage of users. They monitor the performance and error rates using API Gateway’s telemetry capabilities by tracking the access and execution logs, along with emitted metrics. As their confidence grows, they gradually increase the percentage of users sending the v2 header. This approach ensures a controlled migration with minimal risk and ability to quickly rollback by simply removing the header from requests or changing a routing rule.
Sample
Follow the instructions in this GitHub repository to provision the sample in your AWS account. The project illustrates using dynamic routing with API Gateway.
Conclusion
Header-based routing brings significant advantages to API Gateway users. The feature’s backward compatibility ensures a smooth transition path – you can maintain existing base path mappings while gradually adopting Routing Rules, or use both mechanisms simultaneously with the fallback option. This flexibility allows you to migrate at your own pace without disrupting existing applications. The solution is cost-effective, with no additional charges for using Routing Rules on REST APIs. It reduces requirements to leverage extra service and infrastructure for dynamic routing. The priority-based evaluation system provides deterministic routing behavior, making it easier to understand and troubleshoot routing decisions.
To learn more about API Gateway header-based routing see the service documentation.
To learn more about Serverless architectures see Serverless Land.