Spotting Phishing Emails: Essential Tips from Nebosystems

Post Syndicated from Editor original https://nebosystems.eu/spotting-phishing-emails-essential-tips/

Welcome to Nebosystems! We are excited to announce the release of our first video on YouTube: “How to Identify Phishing Emails.” In today’s digital age, protecting yourself from cyber threats is more important than ever. Phishing emails are one of the most common and dangerous types of cyber attacks, but with the right knowledge, you can easily spot and avoid them.

In this video, you’ll learn:

  • How to recognize suspicious sender information.
  • How to identify urgent or threatening language.
  • Tips for checking suspicious links and attachments.
  • The importance of watching for spelling and grammar mistakes.
  • Why legitimate companies will never ask for sensitive information via email.

Stay safe online by following these essential tips. If you find this video helpful, don’t forget to like and subscribe to our YouTube channel for more cybersecurity tips and tricks!

Watch the video now:

For more comprehensive protection, explore our Information Security Services designed to safeguard your digital assets and ensure your business remains secure. Learn more about our services here: Information Security Services.

Stay informed with the latest updates and insights on cybersecurity by visiting our blog: Nebosystems Blog.

For any inquiries or further information, feel free to contact us.

Supermicro AS-1115SV-WTNRT Review 1U AMD EPYC Siena Server

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/supermicro-as-1115sv-wtnrt-review-1u-amd-epyc-siena-broadcom-server/

In our Supermicro AS-1115SV-WTNRT review, we see how this 1U AMD EPYC 8004 platform provides lots of NVMe and expansion due to its WIO design

The post Supermicro AS-1115SV-WTNRT Review 1U AMD EPYC Siena Server appeared first on ServeTheHome.

Scientific Linux 7 reaches end of life

Post Syndicated from corbet original https://lwn.net/Articles/980312/

While the end of support for CentOS 7, which happened on June 30, is
significant, it is also worth taking a moment to reflect on the end of
Scientific Linux 7, which has also just occurred. Scientific Linux
was once a popular RHEL rebuild supported by Fermilab, CERN, DESY, and ETH
Zurich. Development of Scientific Linux stopped with SL7, with the labs
switching to CentOS thereafter, but the SL7 release was supported through
to the bitter end. Thanks are due to all who built and supported
Scientific Linux; you provided a useful and stable platform for many years.

Introducing self-managed data sources for Amazon OpenSearch Ingestion

Post Syndicated from Muthu Pitchaimani original https://aws.amazon.com/blogs/big-data/introducing-self-managed-data-sources-for-amazon-opensearch-ingestion/

Enterprise customers increasingly adopt Amazon OpenSearch Ingestion (OSI) to bring data into Amazon OpenSearch Service for various use cases. These include petabyte-scale log analytics, real-time streaming, security analytics, and searching semi-structured key-value or document data. OSI makes it simple, with straightforward integrations, to ingest data from many AWS services, including Amazon DynamoDB, Amazon Simple Storage Service (Amazon S3), Amazon Managed Streaming for Apache Kafka (Amazon MSK), and Amazon DocumentDB (with MongoDB compatibility).

Today we are announcing support for ingesting data from self-managed OpenSearch/Elasticsearch and Apache Kafka clusters. These sources can either be on Amazon Elastic Compute Cloud (Amazon EC2) or on-premises environments.

In this post, we outline the steps to get started with these sources.

Solution overview

OSI supports the AWS Cloud Development Kit (AWS CDK), AWS CloudFormation, the AWS Command Line Interface (AWS CLI), Terraform, AWS APIs, and the AWS Management Console to deploy pipelines. In this post, we use the console to demonstrate how to create a self-managed Kafka pipeline.

Prerequisites

To make sure OSI can connect and read data successfully, the following conditions should be met:

  • Network connectivity to data sources – OSI is generally deployed in a public network, such as the internet, or in a virtual private cloud (VPC). OSI deployed in a customer VPC is able to access data sources in the same or different VPC and on the internet with an attached internet gateway. If your data sources are in another VPC, common methods for network connectivity include direct VPC peering, using a transit gateway, or using customer managed VPC endpoints powered by AWS PrivateLink. If your data sources are on your corporate data center or other on-premises environment, common methods for network connectivity include AWS Direct Connect and using a network hub like a transit gateway. The following diagram shows a sample configuration of OSI running in a VPC and using Amazon OpenSearch Service as a sink. OSI runs in a service VPC and creates an Elastic Network interface (ENI) in the customer VPC. For self-managed data source these ENIs are used for reading data from on-premises environment. OSI creates an VPC endpoint in the service VPC to send data to the sink.
  • Name resolution for data sources – OSI uses an Amazon Route 53 resolver. This resolver automatically answers queries to names local to a VPC, public domain names on the internet, and records hosted in private hosted zones. If you’re are using a private hosted zone, make sure you have a DHCP option set enabled, attached to the VPC using AmazonProvidedDNS as domain name server. For more information, see Work with DHCP option sets. Additionally, you can use resolver inbound and outbound endpoints if you need a complex resolution schemes with conditions that are beyond a simple private hosted zone.
  • Certificate verification for data source names – OSI supports only SASL_SSL for transport for Apache Kafka source. Within SASL, Amazon OpenSearch Service supports most authentication mechanisms like PLAIN, SCRAM, IAM, GSAPI and others. When using SASL_SSL, make sure you have access to certificates needed for OSI to authenticate. For self-managed OpenSearch data sources, make sure verifiable certificates are installed on the clusters. Amazon OpenSearch Service doesn’t support insecure communication between OSI and OpenSearch. Certificate verification cannot be turned off. In particular, the “insecure” configuration option is not supported.
  • Access to AWS Secrets Manager – OSI uses AWS Secrets Manager to retrieve credentials and certificates needed to communicate with self-managed data sources. For more information, see Create and manage secrets with AWS Secrets Manager.
  • IAM role for pipelines – You need an AWS Identity and Access Management (IAM) pipeline role to write to data sinks. For more information, see Identity and Access Management for Amazon OpenSearch Ingestion.

Create a pipeline with self-managed Kafka as a source

After you complete the prerequisites, you’re ready to create a pipeline for your data source. Complete the following steps:

  1. On the OpenSearch Service console, choose Pipelines under Ingestion in the navigation pane.
  2. Choose Create pipeline.
  3. Choose Streaming under Use case in the navigation pane.
  4. Select Self managed Apache Kafka under Ingestion pipeline blueprints and choose Select blueprint.

This will populate a sample configuration for this pipeline.

  1. Provide a name for this pipeline and choose the appropriate pipeline capacity.
  2. Under Pipeline configuration, provide your pipeline configuration in YAML format. The following code snippet shows sample configuration in YAML for SASL_SSL authentication:
    version: '2'
    kafka-pipeline:
      source:
        kafka:
          acknowledgments: true
          bootstrap_servers:
            - 'node-0.example.com:9092'
          encryption:
            type: "ssl"
            certificate: '${{aws_secrets:kafka-cert}}'
            
          authentication:
            sasl:
              plain:
                username: '${{aws_secrets:secrets:username}}'
                password: '${{aws_secrets:secrets:password}}'
          topics:
            - name: on-prem-topic
              group_id: osi-group-1
      processor:
        - grok:
            match:
              message:
                - '%{COMMONAPACHELOG}'
        - date:
            destination: '@timestamp'
            from_time_received: true
      sink:
        - opensearch:
            hosts: ["https://search-domain-12345567890.us-east-1.es.amazonaws.com"]
            aws:
              region: us-east-1
              sts_role_arn: 'arn:aws:iam::123456789012:role/pipeline-role'
            index: "on-prem-kakfa-index"
    extension:
      aws:
        secrets:
          kafka-cert:
            secret_id: kafka-cert
            region: us-east-1
            sts_role_arn: 'arn:aws:iam::123456789012:role/pipeline-role'
          secrets:
            secret_id: secrets
            region: us-east-1
            sts_role_arn: 'arn:aws:iam::123456789012:role/pipeline-role'

  1. Choose Validate pipeline and confirm there are no errors.
  2. Under Network configuration, choose Public access or VPC access. (For this post, we choose VPC access).
  3. If you chose VPC access, specify your VPC, subnets, and an appropriate security group so OSI can reach the outgoing ports for the data source.
  4. Under VPC attachment options, select Attach to VPC and choose an appropriate CIDR range.

OSI resources are created in a service VPC managed by AWS that is separate from the VPC you chose in the last step. This selection allows you to configure what CIDR ranges OSI should use inside this service VPC. The choice exists so you can make sure there is no address collision between CIDR ranges in your VPC that is attached to your on-premises network and this service VPC. Many pipelines in your account can share same CIDR ranges for this service VPC.

  1. Specify any optional tags and log publishing options, then choose Next.
  2. Review the configuration and choose Create pipeline.

You can monitor the pipeline creation and any log messages in the Amazon CloudWatch Logs log group you specified. Your pipeline should now be successfully created. For more information about how to provision capacity for the performance of this pipeline, see the section Recommended Compute Units (OCUs) for the MSK pipeline in Introducing Amazon MSK as a source for Amazon OpenSearch Ingestion.

Create a pipeline with self-managed OpenSearch as a source

The steps for creating a pipeline for self-managed OpenSearch are similar to the steps for creating one for Kafka. During the blueprint selection, choose Data Migration under Use case and select Self managed OpenSearch/Elasticsearch. OpenSearch Ingestion can source data from all versions of OpenSearch and Elasticsearch from version 7.0  to  version 7.10.

The following blueprint shows a sample configuration YAML for this data source:

version: "2"
opensearch-migration-pipeline:
  source:
    opensearch:
      acknowledgments: true
      hosts: [ "https://node-0.example.com:9200" ]
      username: "${{aws_secrets:secret:username}}"
      password: "${{aws_secrets:secret:password}}"
      indices:
        include:
        - index_name_regex: "opensearch_dashboards_sample_data*"
        exclude:
          - index_name_regex: '\..*'
  sink:
    - opensearch:
        hosts: [ "https://search-domain-12345567890.us-east-1.es.amazonaws.com" ]
        aws:
          sts_role_arn: "arn:aws:iam::123456789012:role/pipeline-role"
          region: "us-east-1"
        index: "on-prem-os"
extension:
  aws:
    secrets:
      secret:
        secret_id: "self-managed-os-credentials"
        region: "us-east-1"
        sts_role_arn: "arn:aws:iam::123456789012:role/pipeline-role"
        refresh_interval: PT1H

Considerations for self-managed OpenSearch data source

Certificates installed on the OpenSearch cluster need to be verifiable for OSI to connect to this data source before reading data. Insecure connections are currently not supported.

After you’re connected, make sure the cluster has sufficient read bandwidth to allow for OSI to read data. Use the Min and Max OCU setting to limit OSI read bandwidth consumption. Your read bandwidth will vary depending upon data volume, number of indexes, and provisioned OCU capacity. Start small and increase the number of OCUs to balance between available bandwidth and acceptable migration time.

This source is typically meant for one-time migration of data and not as continuous ingestion to keep data in sync between data sources and sinks.

OpenSearch Service domains support remote reindexing, but that consumes resources in your domains. Using OSI will move this compute out of the domain, and OSI can achieve significantly higher bandwidth than remote reindexing, thereby resulting in faster migration times.

OSI doesn’t support deferred replay or traffic recording today; refer to Migration Assistant for Amazon OpenSearch Service if your migration needs those capabilities.

Conclusion

In this post, we introduced self-managed sources for OpenSearch Ingestion that enable you to ingest data from corporate data centers or other on-premises environments. OSI also supports various other data sources and integrations. Refer to Working with Amazon OpenSearch Ingestion pipeline integrations to learn about these other data sources.


About the Authors

Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.

Arjun Nambiar is a Product Manager with Amazon OpenSearch Service. He focuses on ingestion technologies that enable ingesting data from a wide variety of sources into Amazon OpenSearch Service at scale. Arjun is interested in large-scale distributed systems and cloud-centered technologies, and is based out of Seattle, Washington.

Upcoming Book on AI and Democracy

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/upcoming-book-on-ai-and-democracy.html

If you’ve been reading my blog, you’ve noticed that I have written a lot about AI and democracy, mostly with my co-author Nathan Sanders. I am pleased to announce that we’re writing a book on the topic.

This isn’t a book about deep fakes, or misinformation. This is a book about what happens when AI writes laws, adjudicates disputes, audits bureaucratic actions, assists in political strategy, and advises citizens on what candidates and issues to support. It’s a book that tries to look into what an AI-assisted democratic system might look like, and then at how to best ensure that we make use of the good parts while avoiding the bad parts.

This is what I talked about in my RSA Conference speech last month, which you can both watch and read. (You can also read earlier attempts at this idea.)

The book will be published by MIT Press sometime in fall 2025, with an open-access digital version available a year after that. (It really can’t be published earlier. Nothing published this year will rise above the noise of the US presidential election, and anything published next spring will have to go to press without knowing the results of that election.)

Right now, the organization of the book is in six parts:

AI-Assisted Politicians
AI-Assisted Legislators
The AI-Assisted Administration
The AI-Assisted Legal System
AI-Assisted Citizens
Getting the Future We Want

It’s too early to share a more detailed table of contents, but I would like help thinking about titles. Below are my current list of brainstorming ideas: both titles and subtitles. Please mix and match, or suggest your own in the comments. No idea is too far afield, because anything can spark more ideas.

Titles:

AI and Democracy
Democracy with AI
Democracy after AI
Democratia ex Machina
Democracy ex Machina
E Pluribus, Machina
Democracy and the Machines
Democracy with Machines
Building Democracy with Machines
Democracy in the Loop
We the People + AI
Artificial Democracy
AI Enhanced Democracy
The State of AI
Citizen AI

Trusting the Bots
Trusting the Computer
Trusting the Machine

The End of the Beginning
Sharing Power
Better Run
Speed, Scale, Scope, and Sophistication
The New Model of Governance
Model Citizen
Artificial Individualism

Subtitles:

How AI Upsets the Power Balances of Democracy
Twenty (or So) Ways AI will Change Democracy
Reimagining Democracy for the Age of AI
Who Wins and Loses
How Democracy Thrives in an AI-Enhanced World
Ensuring that AI Enhances Democracy and Doesn’t Destroy It
How AI Will Change Politics, Legislating, Bureaucracy, Courtrooms, and Citizens
AI’s Transformation of Government, Citizenship, and Everything In-Between
Remaking Democracy, from Voting to Legislating to Waiting in Line
How to Make Democracy Work for People in an AI Future
How AI Will Totally Reshape Democracies and Democratic Institutions
Who Wins and Loses when AI Governs
How to Win and Not Lose With AI as a Partner
AI’s Transformation of Democracy, for Better and for Worse
How AI Can Improve Society and Not Destroy It
How AI Can Improve Society and Not Subvert It
Of the People, for the People, with a Whole lot of AI
How AI Will Reshape Democracy
How the AI Revolution Will Reshape Democracy

Combinations:

Imagining a Thriving Democracy in the Age of AI: How Technology Enhances Democratic Ideals and Nurtures a Society that Serves its People

Making Model Citizens: How to Put AI to Use to Help Democracy
Modeling Citizenship: Who Wins and Who Loses when AI Transforms Democracy
A Model for Government: Democracy with AI, and How to Make it Work for Us

AI of, By, and for the People: How Artificial Intelligence will reshape Democracy
The (AI) Political Revolution: Speed, Scale, Scope, Sophistication, and our Democracy
Speed, Scale, Scope, Sophistication: The AI Democratic Revolution
The Artificial Political Revolution: X Ways AI will Change Democracy…Forever

EDITED TO ADD (7/10): More options:

The Silicon Realignment: The Future of Political Power in a Digital World
Political Machines
EveryTHING is political

Amazon MWAA best practices for managing Python dependencies

Post Syndicated from Mike Ellis original https://aws.amazon.com/blogs/big-data/amazon-mwaa-best-practices-for-managing-python-dependencies/

Customers with data engineers and data scientists are using Amazon Managed Workflows for Apache Airflow (Amazon MWAA) as a central orchestration platform for running data pipelines and machine learning (ML) workloads. To support these pipelines, they often require additional Python packages, such as Apache Airflow Providers. For example, a pipeline may require the Snowflake provider package for interacting with a Snowflake warehouse, or the Kubernetes provider package for provisioning Kubernetes workloads. As a result, they need to manage these Python dependencies efficiently and reliably, providing compatibility with each other and the base Apache Airflow installation.

Python includes the tool pip to handle package installations. To install a package, you add the name to a special file named requirements.txt. The pip install command instructs pip to read the contents of your requirements file, determine dependencies, and install the packages. Amazon MWAA runs the pip install command using this requirements.txt file during initial environment startup and subsequent updates. For more information, see How it works.

Creating a reproducible and stable requirements file is key for reducing pip installation and DAG errors. Additionally, this defined set of requirements provides consistency across nodes in an Amazon MWAA environment. This is most important during worker auto scaling, where additional worker nodes are provisioned and having different dependencies could lead to inconsistencies and task failures. Additionally, this strategy promotes consistency across different Amazon MWAA environments, such as dev, qa, and prod.

This post describes best practices for managing your requirements file in your Amazon MWAA environment. It defines the steps needed to determine your required packages and package versions, create and verify your requirements.txt file with package versions, and package your dependencies.

Best practices

The following sections describe the best practices for managing Python dependencies.

Specify package versions in the requirements.txt file

When creating a Python requirements.txt file, you can specify just the package name, or the package name and a specific version. Adding a package without version information instructs the pip installer to download and install the latest available version, subject to compatibility with other installed packages and any constraints. The package versions selected during environment creation may be different than the version selected during an auto scaling event later on. This version change can create package conflicts leading to pip install errors. Even if the updated package installs properly, code changes in the package can affect task behavior, leading to inconsistencies in output. To avoid these risks, it’s best practice to add the version number to each package in your requirements.txt file.

Use the constraints file for your Apache Airflow version

A constraints file contains the packages, with versions, verified to be compatible with your Apache Airflow version. This file adds an additional validation layer to prevent package conflicts. Because the constraints file plays such an important role in preventing conflicts, beginning with Apache Airflow v2.7.2 on Amazon MWAA, your requirements file must include a --constraint statement. If a --constraint statement is not supplied, Amazon MWAA will specify a compatible constraints file for you.

Constraint files are available for each Airflow version and Python version combination. The URLs have the following form:

https://raw.githubusercontent.com/apache/airflow/constraints-${AIRFLOW_VERSION}/constraints-${PYTHON_VERSION}.txt

The official Apache Airflow constraints are guidelines, and if your workflows require newer versions of a provider package, you may need to modify your constraints file and include it in your DAG folder. When doing so, the best practices outlined in this post become even more important to guard against package conflicts.

Create a .zip archive of all dependencies

Creating a .zip file containing the packages in your requirements file and specifying this as the package repository source makes sure the exact same wheel files are used during your initial environment setup and subsequent node configurations. The pip installer will use these local files for installation rather than connecting to the external PyPI repository.

Test the requirements.txt file and dependency .zip file

Testing your requirements file before release to production is key to avoiding installation and DAG errors. Testing both locally, with the MWAA local runner, and in a dev or staging Amazon MWAA environment, are best practices before deploying to production. You can use continuous integration and delivery (CI/CD) deployment strategies to perform the requirements and package installation testing, as described in Automating a DAG deployment with Amazon Managed Workflows for Apache Airflow.

Solution overview

This solution uses the MWAA local runner, an open source utility that replicates an Amazon MWAA environment locally. You use the local runner to build and validate your requirements file, and package the dependencies. In this example, you install the snowflake and dbt-cloud provider packages. You then use the MWAA local runner and a constraints file to determine the exact version of each package compatible with Apache Airflow. With this information, you then update the requirements file, pinning each package to a version, and retest the installation. When you have a successful installation, you package your dependencies and test in a non-production Amazon MWAA environment.

We use MWAA local runner v2.8.1 for this walkthrough and walk through the following steps:

  1. Download and build the MWAA local runner.
  2. Create and test a requirements file with package versions.
  3. Package dependencies.
  4. Deploy the requirements file and dependencies to a non-production Amazon MWAA environment.

Prerequisites

For this walkthrough, you should have the following prerequisites:

Set up the MWAA local runner

First, you download the MWAA local runner version matching your target MWAA environment, then you build the image.

Complete the following steps to configure the local runner:

  1. Clone the MWAA local runner repository with the following command:
    git clone [email protected]:aws/aws-mwaa-local-runner.git -b v2.8.1

  2. With Docker running, build the container with the following command:
    cd aws-mwaa-local-runner
     ./mwaa-local-env build-image

Create and test a requirements file with package versions

Building a versioned requirements file makes sure all Amazon MWAA components have the same package versions installed. To determine the compatible versions for each package, you start with a constraints file and an un-versioned requirements file, allowing pip to resolve the dependencies. Then you create your versioned requirements file from pip’s installation output.

The following diagram illustrates this workflow.

Requirements file testing process

To build an initial requirements file, complete the following steps:

  1. In your MWAA local runner directory, open requirements/requirements.txt in your preferred editor.

The default requirements file will look similar to the following:

--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-mysql==5.5.1
  1. Replace the existing packages with the following package list:
--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake
apache-airflow-providers-dbt-cloud[http]
  1. Save requirements.txt.
  2. In a terminal, run the following command to generate the pip install output:
./mwaa-local-env test-requirements

test-requirements runs pip install, which handles resolving the compatible package versions. Using a constraints file makes sure the selected packages are compatible with your Airflow version. The output will look similar to the following:

Successfully installed apache-airflow-providers-dbt-cloud-3.5.1 apache-airflow-providers-snowflake-5.2.1 pyOpenSSL-23.3.0 snowflake-connector-python-3.6.0 snowflake-sqlalchemy-1.5.1 sortedcontainers-2.4.0

The message beginning with Successfully installed is the output of interest. This shows which dependencies, and their specific version, pip installed. You use this list to create your final versioned requirements file.

Your output will also contain Requirement already satisfied messages for packages already available in the base Amazon MWAA environment. You do not add these packages to your requirements.txt file.

  1. Update the requirements file with the list of versioned packages from the test-requirements command. The updated file will look similar to the following code:
--constraint "https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0

Next, you test the updated requirements file to confirm no conflicts exist.

  1. Rerun the requirements-test function:
./mwaa-local-env test-requirements

A successful test will not produce any errors. If you encounter dependency conflicts, return to the previous step and update the requirements file with additional packages, or package versions, based on pip’s output.

Package dependencies

If your Amazon MWAA environment has a private webserver, you must package your dependencies into a .zip file, upload the file to your S3 bucket, and specify the package location in your Amazon MWAA instance configuration. Because a private webserver can’t access the PyPI repository through the internet, pip will install the dependencies from the .zip file.

If you’re using a public webserver configuration, you also benefit from a static .zip file, which makes sure the package information remains unchanged until it is explicitly rebuilt.

This process uses the versioned requirements file created in the previous section and the package-requirements feature in the MWAA local runner.

To package your dependencies, complete the following steps:

  1. In a terminal, navigate to the directory where you installed the local runner.
  2. Download the constraints file for your Python version and your version of Apache Airflow and place it in the plugins directory. For this post, we use Python 3.11 and Apache Airflow v2.8.1:
curl -o plugins/constraints-2.8.1-3.11.txt https://raw.githubusercontent.com/apache/airflow/constraints-2.8.1/constraints-3.11.txt
  1. In your requirements file, update the constraints URL to the local downloaded file.

The –-constraint statement instructs pip to compare the package versions in your requirements.txt file to the allowed version in the constraints file. Downloading a specific constraints file to your plugins directory enables you to control the constraint file location and contents.

The updated requirements file will look like the following code:

--constraint "/usr/local/airflow/plugins/constraints-2.8.1-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0
  1. Run the following command to create the .zip file:
./mwaa-local-env package-requirements

package-requirements creates an updated requirements file named packaged_requirements.txt and zips all dependencies into plugins.zip. The updated requirements file looks like the following code:

--find-links /usr/local/airflow/plugins
--no-index
--constraint "/usr/local/airflow/plugins/constraints-2.8.1-3.11.txt"
apache-airflow-providers-snowflake==5.2.1
apache-airflow-providers-dbt-cloud[http]==3.5.1
pyOpenSSL==23.3.0
snowflake-connector-python==3.6.0
snowflake-sqlalchemy==1.5.1
sortedcontainers==2.4.0

Note the reference to the local constraints file and the plugins directory. The –-find-links statement instructs pip to install packages from /usr/local/airflow/plugins rather than the public PyPI repository.

Deploy the requirements file

After you achieve an error-free requirements installation and package your dependencies, you’re ready to deploy the assets to a non-production Amazon MWAA environment. Even when verifying and testing requirements with the MWAA local runner, it’s best practice to deploy and test the changes in a non-prod Amazon MWAA environment before deploying to production. For more information about creating a CI/CD pipeline to test changes, refer to Deploying to Amazon Managed Workflows for Apache Airflow.

To deploy your changes, complete the following steps:

  1. Upload your requirements.txt file and plugins.zip file to your Amazon MWAA environment’s S3 bucket.

For instructions on specifying a requirements.txt version, refer to Specifying the requirements.txt version on the Amazon MWAA console. For instructions on specifying a plugins.zip file, refer to Installing custom plugins on your environment.

The Amazon MWAA environment will update and install the packages in your plugins.zip file.

After the update is complete, verify the provider package installation in the Apache Airflow UI.

  1. Access the Apache Airflow UI in Amazon MWAA.
  2. From the Apache Airflow menu bar, choose Admin, then Providers.

The list of providers, and their versions, is shown in a table. In this example, the page reflects the installation of apache-airflow-providers-db-cloud version 3.5.1 and apache-airflow-providers-snowflake version 5.2.1. This list only contains the provider packages installed, not all supporting Python packages. Provider packages that are part of the base Apache Airflow installation will also appear in the list. The following image is an example of the package list; note the apache-airflow-providers-db-cloud and apache-airflow-providers-snowflake packages and their versions.

Airflow UI with installed packages

To verify all package installations, view the results in Amazon CloudWatch Logs. Amazon MWAA creates a log stream for the requirements installation and the stream contains the pip install output. For instructions, refer to Viewing logs for your requirements.txt.

A successful installation results in the following message:

Successfully installed apache-airflow-providers-dbt-cloud-3.5.1 apache-airflow-providers-snowflake-5.2.1 pyOpenSSL-23.3.0 snowflake-connector-python-3.6.0 snowflake-sqlalchemy-1.5.1 sortedcontainers-2.4.0

If you encounter any installation errors, you should determine the package conflict, update the requirements file, run the local runner test, re-package the plugins, and deploy the updated files.

Clean up

If you created an Amazon MWAA environment specifically for this post, delete the environment and S3 objects to avoid incurring additional charges.

Conclusion

In this post, we discussed several best practices for managing Python dependencies in Amazon MWAA and how to use the MWAA local runner to implement these practices. These best practices reduce DAG and pip installation errors in your Amazon MWAA environment. For additional details and code examples on Amazon MWAA, visit the Amazon MWAA User Guide and the Amazon MWAA examples GitHub repo.

Apache, Apache Airflow, and Airflow are either registered trademarks or trademarks of the Apache Software Foundation in the United States and/or other countries.


About the Author


Mike Ellis is a Technical Account Manager at AWS and an Amazon MWAA specialist. In addition to assisting customers with Amazon MWAA, he contributes to the Apache Airflow open source project.

Amazon DataZone enhances data discovery with advanced search filtering

Post Syndicated from Chaitanya Vejendla original https://aws.amazon.com/blogs/big-data/amazon-datazone-enhances-data-discovery-with-advanced-search-filtering/

Amazon DataZone, a fully managed data management service, helps organizations catalog, discover, analyze, share, and govern data between data producers and consumers. We are excited to announce the introduction of advanced search filtering capabilities in the Amazon DataZone business data catalog.

With the improved rendering of glossary terms, you can now navigate large sets of terms with ease in an expandable and collapsible hierarchy, reducing the time and effort required to locate specific data assets. The introduction of logical operators (AND and OR) for filtering allows for more precise searches, enabling you to combine multiple criteria in a way that best suits your needs. The descriptive summary of search criteria helps users keep track of their applied filters, making it simple to adjust search parameters on the fly.

In this post, we discuss how these new search filtering capabilities enhance the user experience and boost the accuracy of search results, facilitating the ability to find data quickly.

Challenges

Many of our customers manage vast numbers of data assets within the Amazon DataZone catalog for discoverability. Data producers tag these assets with business glossary terms to classify and enhance discovery. For example, data assets owned by a particular department can be tagged with the glossary term for that department, like “Marketing.”

Data consumers searching for the right data assets use faceted search with various criteria, including business glossary terms, and apply filters to refine their search results. However, finding the right data assets can be challenging, especially when it involves combining multiple filters. Customers wanted more flexibility and precision in their search capabilities, such as:

  • A more intuitive way to navigate through extensive lists of glossary terms
  • The ability to apply more nuanced search logic to refine search results with greater precision
  • A summary of applied filters to effortlessly review and adjust search criteria

New features in Amazon DataZone

With the latest release, Amazon DataZone now supports features that enhance search flexibility and accuracy:

  • Improved rendering of glossary terms – Glossary terms are now displayed in a hierarchical view, providing a more organized structure. You can navigate and select from long lists of glossary terms presented in an expandable and collapsible hierarchy within the search facets. For instance, a data scientist can quickly find specific customer demographic data without sifting through an overwhelming flat list.
  • Logical operators for refined search – You can now choose logical operators to refine your search results, offering greater control and precision. For example, a financial analyst preparing a report on investment performance can use AND logic to combine criteria like investment type and region to pinpoint the exact data needed, or use OR logic to broaden the search to include any investments that meet either criterion.
  • Summary of search criteria – A descriptive summary of applied search filters is now provided, allowing you to review and manage your search criteria with ease. For example, a project manager can quickly adjust filters to find project-related assets matching specific phases or statuses.

These enhancements enable you to better understand the relationships between different search facets, enhancing the overall search experience and making it effortless to find the right data assets.

Use case overview

To demonstrate these search enhancements, we set up a new Amazon DataZone domain with two projects:

  • Marketing project – Publishes campaign-related data assets from the Marketing department. These data assets have been tagged with relevant business glossary terms corresponding to marketing.
  • Sales project – Publishes sales-related datasets from the Sales department. These data assets have been tagged with relevant business glossary terms corresponding to sales.

The following screenshots show examples of the different tagged assets.

In the following sections, we demonstrate the improvements in the user search experience for this use case.

Improved rendering of glossary terms

As a data consumer, you want to discover data assets using the faceted search capability within Amazon DataZone.

The search result panel has been enhanced to display glossaries and glossary terms in a hierarchical fashion. This allows you to expand and collapse sections for a more intuitive search experience.

For example, if you want to find product sales data assets from the Corporate Sales department, you can select the appropriate term within the glossary. The selection criteria and the corresponding result list show a total of 18 data assets, as shown in the following screenshot.

Next, if you want to further refine your search to focus only on the product category of Smartphones, you can do so.

Because OR is the default logical operator for your search within the glossary terms, it lists all the assets that are either part of Corporate Sales or tagged with Smartphones.

Logical operators for refined search

You now have the flexibility to change the default operator to AND to list only those data assets that are part of Corporate Sales and tagged with Smartphones, narrowing down the result set.

Additionally, you can further filter based on the asset type by selecting the available options. When you select Glue Table as your asset type, it defaults to the AND condition across the glossary terms and the asset type filter, thereby showing the data assets that satisfy all the filter conditions.

You also have the flexibility to change the operator to OR across these filters, yielding a more exhaustive list of data assets.

Summary of search criteria

As we showed in the preceding screenshots, the results also display a summary of the filters you applied for the search. This enables you to review and better manage your search criteria.

Conclusion

This post demonstrated new Amazon DataZone search enhancement features that streamline data discovery for a more intuitive user experience. These enhancements are designed to empower data consumers within organizations to make more informed decisions, faster. By streamlining the search process and making it more intuitive, Amazon DataZone continues to support the growing needs of data-driven businesses, helping you unlock the full potential of your data assets.

For more information about Amazon DataZone and to get started, refer to the Amazon DataZone User Guide.


About the authors

Chaitanya Vejendla is a Senior Solutions Architect specialized in DataLake & Analytics primarily working for Healthcare and Life Sciences industry division at AWS. Chaitanya is responsible for helping life sciences organizations and healthcare companies in developing modern data strategies, deploy data governance and analytical applications, electronic medical records, devices, and AI/ML-based applications, while educating customers about how to build secure, scalable, and cost-effective AWS solutions. His expertise spans across data analytics, data governance, AI, ML, big data, and healthcare-related technologies.

Ramesh H Singh is a Senior Product Manager Technical (External Services) at AWS in Seattle, Washington, currently with the Amazon DataZone team. He is passionate about building high-performance ML/AI and analytics products that enable enterprise customers to achieve their critical goals using cutting-edge technology.

Rishabh Asthana is a Front-end Engineer at AWS, working with the Amazon DataZone team based in New York City, USA.

Somdeb Bhattacharjee is an Enterprise Solutions Architect based out of New York, USA focused on helping customers on their cloud journey. He has interest in Databases, Big Data and Analytics.
AWS Weekly Roundup: AI21 Labs’ Jamba-Instruct in Amazon Bedrock, Amazon WorkSpaces Pools, and more (July 1, 2024)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-ai21-labs-jamba-instruct-in-amazon-bedrock-amazon-workspaces-pools-and-more-july-1-2024/

AWS Summit New York is 10 days away, and I am very excited about the new announcements and more than 170 sessions. There will be A Night Out with AWS event after the summit for professionals from the media and entertainment, gaming, and sports industries who are existing Amazon Web Services (AWS) customers or have a keen interest in using AWS Cloud services for their business. You’ll have the opportunity to relax, collaborate, and build new connections with AWS leaders and industry peers.

Let’s look at the last week’s new announcements.

Last week’s launches
Here are the launches that got my attention.

AI21 Labs’ Jamba-Instruct now available in Amazon Bedrock – AI21 Labs’ Jamba-Instruct is an instruction-following large language model (LLM) for reliable commercial use, with the ability to understand context and subtext, complete tasks from natural language instructions, and ingest information from long documents or financial filings. With strong reasoning capabilities, Jamba-Instruct can break down complex problems, gather relevant information, and provide structured outputs to enable uses like Q&A on calls, summarizing documents, building chatbots, and more. For more information, visit AI21 Labs in Amazon Bedrock and the Amazon Bedrock User Guide.

Amazon WorkSpaces Pools, a new feature of Amazon WorkSpaces – You can now create a pool of non-persistent virtual desktops using Amazon WorkSpaces and save costs by sharing them across users who receive a fresh desktop each time they sign in. WorkSpaces Pools provides the flexibility to support shared environments like training labs and contact centers, and some user settings like bookmarks and files stored in a central storage repository such as Amazon Simple Storage Service (Amazon S3) or Amazon FSx can be saved for improved personalization. You can use AWS Auto Scaling to automatically scale the pool of virtual desktops based on usage metrics or schedules. For pricing information, refer to the Amazon WorkSpaces Pricing page.

API-driven, OpenLineage-compatible data lineage visualization in Amazon DataZone (preview) – Amazon DataZone introduces a new data lineage feature that allows you to visualize how data moves from source to consumption across organizations. The service captures lineage events from OpenLineage-enabled systems or through API to trace data transformations. Data consumers can gain confidence in an asset’s origin, and producers can assess the impact of changes by understanding its consumption through the comprehensive lineage view. Additionally, Amazon DataZone versions lineage with each event to enable visualizing lineage at any point in time or comparing transformations across an asset or job’s history. To learn more, visit Amazon DataZone, read my News Blog post, and get started with data lineage documentation.

Knowledge Bases for Amazon Bedrock now offers observability logs – You can now monitor knowledge ingestion logs through Amazon CloudWatch, S3 buckets, or Amazon Data Firehose streams. This provides enhanced visibility into whether documents were successfully processed or encountered failures during ingestion. Having these comprehensive insights promptly ensures that you can efficiently determine when your documents are ready for use. For more details on these new capabilities, refer to the Knowledge Bases for Amazon Bedrock documentation.

Updates and expansion to the AWS Well-Architected Framework and Lens Catalog – We announced updates to the AWS Well-Architected Framework and Lens Catalog to provide expanded guidance and recommendations on architectural best practices for building secure and resilient cloud workloads. The updates reduce redundancies and enhance consistency in resources and framework structure. The Lens Catalog now includes the new Financial Services Industry Lens and updates to the Mergers and Acquisitions Lens. We also made important updates to the Change Enablement in the Cloud whitepaper. You can use the updated Well-Architected Framework and Lens Catalog to design cloud architectures optimized for your unique requirements by following current best practices.

Cross-account machine learning (ML) model sharing support in Amazon SageMaker Model Registry – Amazon SageMaker Model Registry now integrates with AWS Resource Access Manager (AWS RAM), allowing you to easily share ML models across AWS accounts. This helps data scientists, ML engineers, and governance officers access models in different accounts like development, staging, and production. You can share models in Amazon SageMaker Model Registry by specifying the model in the AWS RAM console and granting access to other accounts. This new feature is now available in all AWS Regions where SageMaker Model Registry is available except GovCloud Regions. To learn more, visit the Amazon SageMaker Developer Guide.

AWS CodeBuild supports Arm-based workloads using AWS Graviton3 – AWS CodeBuild now supports natively building and testing Arm workloads on AWS Graviton3 processors without additional configuration, providing up to 25% higher performance and 60% lower energy usage than previous Graviton processors. To learn more about CodeBuild’s support for Arm, visit our AWS CodeBuild User Guide.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

We launched existing services and instance types in additional Regions:

Other AWS news
Here are some additional news items that you might find interesting:

Top reasons to build and scale generative AI applications on Amazon Bedrock – Check out Jeff Barr’s video, where he discusses why our customers are choosing Amazon Bedrock to build and scale generative artificial intelligence (generative AI) applications that deliver fast value and business growth. Amazon Bedrock is becoming a preferred platform for building and scaling generative AI due to its features, innovation, availability, and security. Leading organizations across diverse sectors use Amazon Bedrock to speed their generative AI work, like creating intelligent virtual assistants, creative design solutions, document processing systems, and a lot more.

Four ways AWS is engineering infrastructure to power generative AI – We continue to optimize our infrastructure to support generative AI at scale through innovations like delivering low-latency, large-scale networking to enable faster model training, continuously improving data center energy efficiency, prioritizing security throughout our infrastructure design, and developing custom AI chips like AWS Trainium to increase computing performance while lowering costs and energy usage. Read the new blog post about how AWS is engineering infrastructure for generative AI.

AWS re:Inforce 2024 re:Cap – It’s been 2 weeks since AWS re:Inforce 2024, our annual cloud-security learning event. Check out the summary of the event prepared by Wojtek.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. To learn more about future AWS Summit events, visit the AWS Summit page. Register in your nearest city: New York (July 10), Bogotá (July 18), and Taipei (July 23–24).

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are in Cameroon (July 13), Aotearoa (August 15), and Nigeria (August 24).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

[$] Arithmetic overflow mitigation in the kernel

Post Syndicated from daroc original https://lwn.net/Articles/979747/

On May 7, Kees Cook sent

a proposal
to the linux-kernel mailing list, asking for the kernel
developers to start
working on a way to mitigate unintentional arithmetic overflow, which has been a
source of many bugs. This is not the first time Cook has made a request along
these lines; he sent a related patch set in
January 2024.
Several core developers objected to the plan for different
reasons. After receiving their feedback,
Cook modified his approach to tackle the problem
in a series of smaller steps.

Security updates for Monday

Post Syndicated from corbet original https://lwn.net/Articles/980252/

Security updates have been issued by Debian (dcmtk, edk2, emacs, glibc, gunicorn, libmojolicious-perl, openssh, org-mode, pdns-recursor, tryton-client, and tryton-server), Fedora (freeipa, kitty, libreswan, mingw-gstreamer1, mingw-gstreamer1-plugins-bad-free, mingw-gstreamer1-plugins-base, mingw-gstreamer1-plugins-good, mingw-poppler, and mingw-python-urllib3), Gentoo (cpio, cryptography, GNU Emacs, Org Mode, GStreamer, GStreamer Plugins, Liferea, Pixman, SDL_ttf, SSSD, and Zsh), Oracle (pki-core), Red Hat (httpd:2.4, libreswan, and pki-core), SUSE (glib2 and kubevirt, virt-api-container, virt-controller-container, virt-exportproxy-container, virt-exportserver-container, virt-handler-container, virt-launcher-container, virt-libguestfs-t), and Ubuntu (espeak-ng, libcdio, and openssh).

Serious vulnerability fixed with OpenSSH 9.8

Post Syndicated from corbet original https://lwn.net/Articles/980211/

OpenSSH 9.8 has been
released, fixing an ugly vulnerability:

Successful exploitation has been demonstrated on 32-bit Linux/glibc
systems with ASLR. Under lab conditions, the attack requires on
average 6-8 hours of continuous connections up to the maximum the
server will accept. Exploitation on 64-bit systems is believed to
be possible but has not been demonstrated at this time. It’s likely
that these attacks will be improved upon.

Exploitation on non-glibc systems is conceivable but has not been
examined.

There is a
configuration workaround
for systems that cannot be updated, though it
has its own problems. See this Qualys
advisory
for more details.

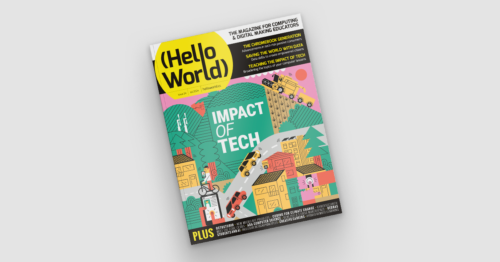
Hello World #24 out now: Impact of tech

Post Syndicated from Meg Wang original https://www.raspberrypi.org/blog/hello-world-24-out-now-impact-of-tech/

Do you remember a time before social media? Mobile phones? Email? We are surrounded by digital technology, and new applications impact our lives whether we engage with them or not. Issue 24 of Hello World, out today for free, gives you ideas for how to help your learners think openly and critically about technology.

Teaching about the impact of technology 

For learners to become informed, empowered citizens, they need to understand the impact technology has on them as individuals, and on society as a whole. In our brand-new issue of Hello World, educators share insights from their work in and around classrooms that will help you engage your learners in learning about and discussing the impact of tech.

For example:

  • Jasmeen Kanwal and the team at Data Education in Schools share their resources for how young people can start to learn the skills they need to change the world with data
  • Julie York writes about how incorporating AI education into any classroom can help students prepare for future careers
  • Ben Hall discusses whether technology is divisive or inclusive, and how you can encourage students to think critically about it
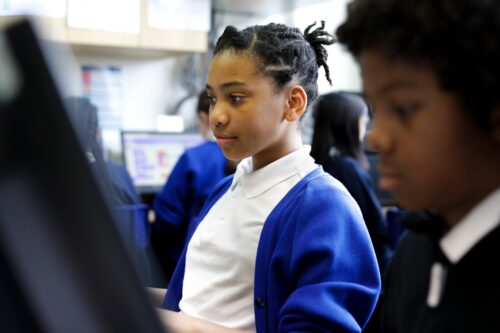
Two learners in a computing classroom.

This issue also includes stories on how educators use technology to create a positive impact for learners:

  • Yolanda Payne tells you how she’s using teaching experiences from the COVID-19 pandemic to bring better remote learning to communities in Georgia, USA, and in the US Virgin Islands
  • Mitchel Resnik and Natalie Rusk from Lifelong Kindergarten group at MIT Media Lab introduce their new free mobile app, OctoStudio, and how it helps learners and educators in underresourced areas get creative with code

And there is lots more for you to discover in issue 24.

The issue also covers how you can make time to teach about the impact of technology in an already packed curriculum. Sway Grantham, Senior Learning Manager at the Raspberry Pi Foundation, says in her article:

“As adults, it is easy for us to see the impact technology has had on society and on our lives. Yet when I tell pupils that, within my lifetime, it wasn’t always illegal to hold your mobile phone to your ear and have a call while driving, they are horrified. They are living in the now and don’t yet have the perspective to allow them to see the change that has happened. However, knowing the impact of technology allows us to learn from previous mistakes, to make decisions around ethical behaviour (such as using a phone while driving), and to critically engage in real-world issues.

As teachers, allocating some time to this topic throughout the year can seem challenging, but with a few small changes, the impact might be more than you can imagine.”

Share your thoughts & subscribe to Hello World

With so many aspects of life impacted by technology, computing educators play a crucial role in supporting young people to become informed, empowered citizens. We hope you enjoy this issue of Hello World and find it useful in your teaching.

The post Hello World #24 out now: Impact of tech appeared first on Raspberry Pi Foundation.

Model Extraction from Neural Networks

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/07/model-extraction-from-neural-networks.html

A new paper, “Polynomial Time Cryptanalytic Extraction of Neural Network Models,” by Adi Shamir and others, uses ideas from differential cryptanalysis to extract the weights inside a neural network using specific queries and their results. This is much more theoretical than practical, but it’s a really interesting result.

Abstract:

Billions of dollars and countless GPU hours are currently spent on training Deep Neural Networks (DNNs) for a variety of tasks. Thus, it is essential to determine the difficulty of extracting all the parameters of such neural networks when given access to their black-box implementations. Many versions of this problem have been studied over the last 30 years, and the best current attack on ReLU-based deep neural networks was presented at Crypto’20 by Carlini, Jagielski, and Mironov. It resembles a differential chosen plaintext attack on a cryptosystem, which has a secret key embedded in its black-box implementation and requires a polynomial number of queries but an exponential amount of time (as a function of the number of neurons). In this paper, we improve this attack by developing several new techniques that enable us to extract with arbitrarily high precision all the real-valued parameters of a ReLU-based DNN using a polynomial number of queries and a polynomial amount of time. We demonstrate its practical efficiency by applying it to a full-sized neural network for classifying the CIFAR10 dataset, which has 3072 inputs, 8 hidden layers with 256 neurons each, and about 1.2 million neuronal parameters. An attack following the approach by Carlini et al. requires an exhaustive search over 2^256 possibilities. Our attack replaces this with our new techniques, which require only 30 minutes on a 256-core computer.

The collective thoughts of the interwebz