Tag Archives: AWS Well-Architected Framework

Eclipse Dataspace Components on AWS: Cost optimization strategies

Post Syndicated from Jorge Hernández Suárez original https://aws.amazon.com/blogs/architecture/eclipse-dataspace-components-on-aws-cost-optimization-strategies/

When you deploy Eclipse Dataspace Components (EDC) connectors on AWS, one of the first challenges you face is predicting and controlling the cost of the required infrastructure. Without clear benchmarks, it is difficult to make informed decisions about workload sizing, environment configuration, and long-term investment.

Part 1 of this 3-part blog series covered the fundamentals of data space architectures and the EDC per the International Data Space Association’s (IDSA) standards. Part 2 explored production-ready architecture patterns for deploying EDC connectors on Amazon Web Services (AWS), discussing operational excellence, security, and reliability principles. This final post covers the remaining three AWS Well-Architected Framework pillars: Performance Efficiency, Cost Optimization, and Sustainability.

In this post, you will learn which AWS services drive cost in an EDC connector deployment, how to estimate monthly costs for business-critical and non-critical workloads, and how to apply optimization strategies that can reduce your spending by up to 58%.

Understanding cost drivers in data space deployments

Data spaces are secure and sovereign data environments that enable data sharing across independent organizations. With these architectures, you can collaborate with external organizations while maintaining full control over your data and compliance with data sovereignty principles. Your infrastructure costs can vary significantly. The main factors are your performance and reliability requirements, along with data volume and velocity across the network. It’s also important to distinguish between two types of infrastructure. A Dataspace Governance Authority (DSGA) centrally establishes components such as management, identity, and discovery functions. Participants host other components themselves, including the connector. This blog post focuses only on costs associated with EDC connector deployment on the participant, that is, the data provider and consumer sides.

Fictional usage assumptions

Before diving into the numbers, here are technical and operational assumptions you can use as a baseline for your own estimates.

Technical assumptions

Category Assumption Justification
Data Volume 5 GB per participant Includes 6 months of historical data, and backups
Network Traffic 20 GB/month per participant Data transfers between participants
API Calls 100,000/month per participant Catalog queries, contract negotiations, and data transfers
OAuth Token Requests 1,000/month per participant Machine-to-machine authentication for data plane operations

Table 1: Technical assumptions for EDC connector cost estimation

Operational assumptions

  • Single AWS Region: Spain (eu-south-2)
  • Operating hours: 24/7/365.
  • Growth rate: Not considered in baseline estimates.
  • Disaster recovery: Automated backups only (no cross-region replication)

Deployment architecture and scenarios

Figure 1 shows the reference architecture for deploying production-ready EDC connectors on AWS, covered in depth in Part 2 of this series.
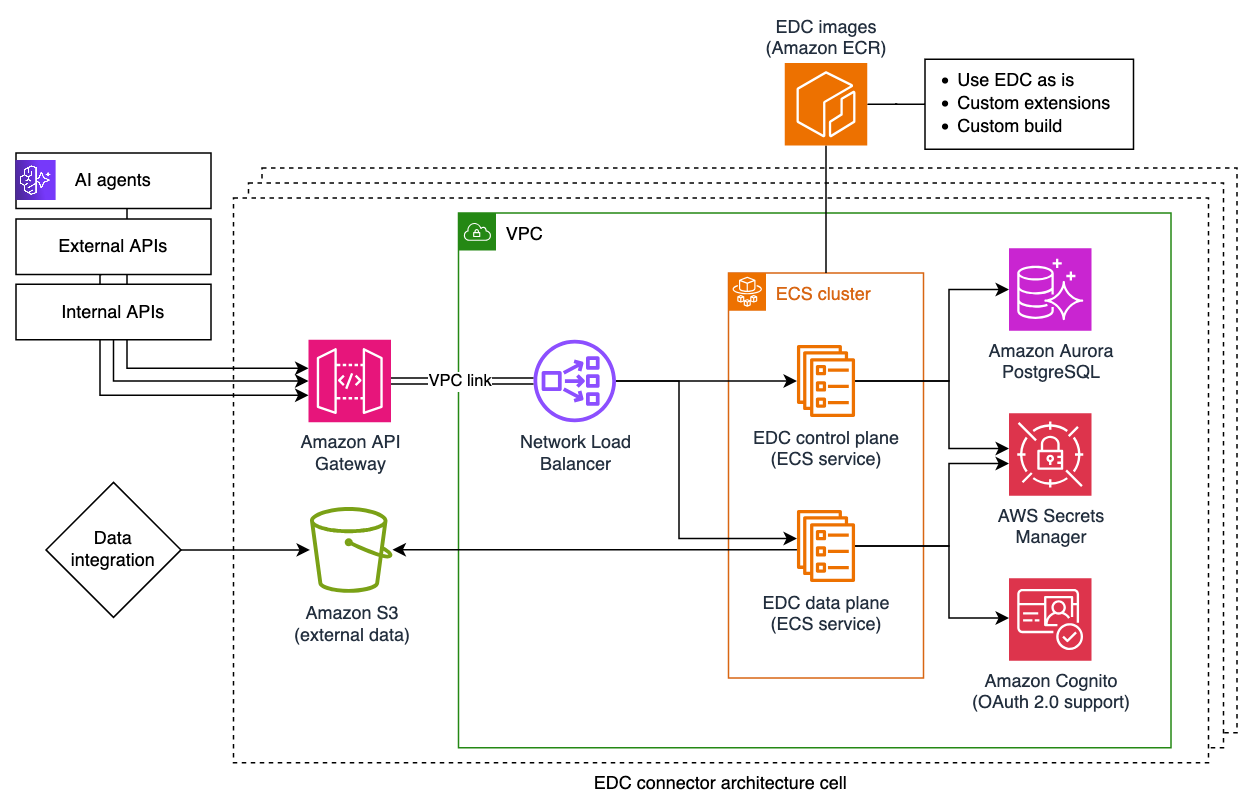
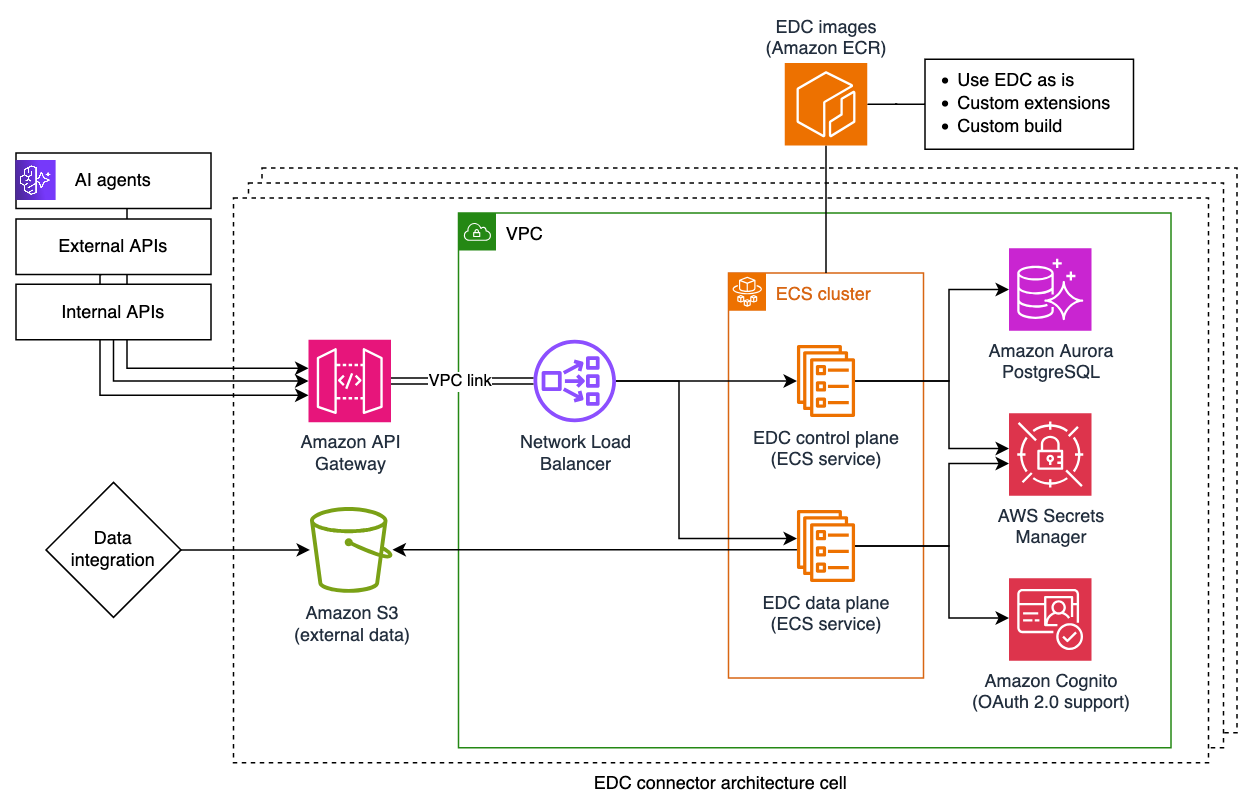
Production-ready EDC connector deployment architecture diagram showing AWS services including Amazon ECS, Amazon Aurora, Network Load Balancer, and supporting services

Figure 1: Production-ready EDC connector deployment

This post considers two cost scenarios depending on the criticality of the workload:

  • Business-critical workloads: Designed for high availability, performance, and reliability of use cases supporting critical business functions.
  • Non-critical workloads: Designed for use cases that tolerate interruptions, testing environments, or production workloads where brief disruptions are acceptable.

Both scenarios follow the architecture patterns described in Part 2 of this post series, with the primary differences being in sizing of compute and database resources.

Cost estimation: Business-critical workloads

Note: These estimates use the assumptions above and illustrate the relative cost contribution of each service. Your actual costs may vary based on your specific usage patterns, data volumes and regional pricing. This post highlights which components represent the highest cost drivers and therefore come with the highest potential for optimization.

AWS Service Configuration Monthly Cost (USD)
Amazon Aurora PostgreSQL-Compatible Edition db.r6g.large (2 vCPU, 16 GB), 20 GB storage + 10 GB backup 276.00
Amazon Elastic Container Service (Amazon ECS) with AWS Fargate 2 vCPU, 4 GB RAM, always on 83.00
Network Load Balancer 20 GB processed data 20.00
AWS Secrets Manager 10 secrets 4.00
Amazon Cognito 1K machine-to-machine (M2M) token requests 2.25
Amazon Elastic Container Registry (Amazon ECR) 2 GB storage, 10 GB transfer 1.00
Amazon API Gateway 100K REST API calls 0.40
Amazon Simple Storage Service (Amazon S3) 5 GB Standard tier 0.10
Total 387.00

Table 2: Estimated monthly cost for business-critical EDC connector deployment

These estimates help identify where your budget goes and where optimization has the most impact. In the business-critical scenario, the main cost driver is Amazon Aurora PostgreSQL. The db.r6g.large configuration is selected for constant workloads that require reliability and speed with high memory and performance. Amazon ECS with AWS Fargate is the second largest cost contributor as it runs containers continuously to maintain environment availability. Network Load Balancer represents a third notable cost component, while the remaining services contribute only a small portion of the total cost.

Cost estimation: Non-critical workloads

If you are running development, testing, or experimentation environments, you can reduce costs by up to 58% through rightsizing and use of Amazon EC2 Spot capacity.

AWS Service Configuration Monthly Cost (USD)
Amazon Aurora PostgreSQL-Compatible db.t4g.medium (2 vCPU, 4 GB), 20 GB storage + 10 GB backup 110.00
Amazon ECS with AWS Fargate Spot 2 vCPU, 4 GB RAM, always on 26.00
Network Load Balancer 20 GB processed data 20.00
AWS Secrets Manager 10 secrets 4.00
Amazon Cognito 1K M2M token requests 2.25
Amazon ECR 2 GB storage, 10 GB transfer 1.00
Amazon API Gateway 100K REST API calls 0.40
Amazon S3 5 GB Standard tier 0.10
Total 164.00

Table 3: Estimated monthly cost for non-critical EDC connector deployment

These figures show that a non-critical configuration can cut costs significantly while maintaining the same data throughput and API capacity. Costs are reduced through the use of smaller and more flexible resources. Amazon Aurora PostgreSQL remains the main cost driver, but the smaller instance type (db.t4g.medium) reduces cost significantly. From a compute perspective, using Amazon ECS with AWS Fargate Spot capacity cuts costs by almost 70% compared to the business-critical setup. In total, this configuration reduces the monthly cost by approximately 58%, while maintaining identical assumptions for data throughput, API calls, and storage.

Key takeaways on cost optimization

This comparison shows that the primary cost contributors in both scenarios are database, compute and load balancing resources, which represent baseline infrastructure costs rather than usage-based charges. Services like Amazon S3, API Gateway, and data transfer charges contribute marginally to overall costs at these volumes. This cost structure indicates that the architecture scales efficiently with increased usage. As you onboard more use cases and increase data volume and velocity, you get more value from your existing infrastructure investment without proportional cost increases.

Well-Architected pillars: Performance efficiency, cost optimization, and sustainability

Part 2 of this series covered EDC best practices along the Operational Excellence, Security, and Reliability pillars of the AWS Well-Architected Framework. This section covers the remaining three pillars as they apply to EDC deployments.

Performance efficiency

Right-size compute resources: Match your Amazon ECS task definitions to actual workload requirements. Start with smaller configurations and scale up based on observed metrics rather than over-provisioning from the start. Amazon CloudWatch Container Insights provides the visibility needed to make informed sizing decisions.

Use the flexibility of Amazon Aurora: For workloads with variable demand patterns, consider Amazon Aurora Serverless v2 which automatically scales database capacity based on application needs. This eliminates the need to provision for peak capacity while maintaining performance during high-demand periods.

Optimize data transfer patterns: Design your data plane operations to minimize unnecessary data movement. Use Amazon S3 Transfer Acceleration for large transfers across geographic distances and consider data compression where appropriate to reduce both transfer times and costs.

Cost optimization

Reduce compute costs for fault-tolerant workloads: With AWS Fargate Spot, you can save up to 70% for workloads that can tolerate interruptions. Non-critical environments, batch processing, and development workloads are ideal candidates. Implement graceful shutdown handling to manage Spot interruptions effectively.

Lower storage costs over time: Configure Amazon S3 Lifecycle policies to automatically transition infrequently accessed data to lower-cost storage classes such as S3 Intelligent-Tiering or S3 Glacier Instant Retrieval. For EDC connector deployments, historical transfer logs and archived assets are good candidates for tiered storage.

Monitor for unexpected cost increases: Use AWS Cost Explorer and set up AWS Budgets with alerts to help detect unexpected cost increases. Tag EDC-related AWS resources consistently so you can accurately allocate costs and identify optimization opportunities.

Lock in lower rates for predictable workloads: For business-critical connectors with predictable, steady-state usage, Savings Plans for Amazon Aurora and AWS Fargate can provide significant discounts compared to On-Demand pricing.

Sustainability

Optimize resource utilization: Higher utilization of provisioned resources means less waste. Use automatic scaling policies to match capacity with demand and shut down non-production environments outside of business hours when possible.

Select efficient instance types: AWS Graviton-based instances (such as the r6g and t4g families used in our example) deliver better price-performance and energy efficiency compared to equivalent x86 instances. AWS Graviton processors offer improved performance per watt of energy use.

Minimize data movement: Each data transfer consumes energy. Design your data space integrations to avoid redundant transfers, cache frequently accessed catalog data of peers locally using the Federated Catalog, and batch operations where possible to reduce the total number of network round trips.

Summary

By rightsizing AWS infrastructure to match actual compute and database capacity needs, data space participants can achieve significant cost savings without compromising on data security and sovereignty aspects that make data spaces valuable. The comparison between business-critical and non-critical workload configurations demonstrates how AWS services like Amazon Aurora, AWS Fargate Spot, and Amazon S3 can be combined effectively to balance data sovereignty, performance, and cost efficiency.

As data spaces grow in adoption across industries and geographies, understanding these cost dynamics becomes increasingly important as you plan your network participation. The patterns and estimates in this post series offer a foundation for planning your cross-organizational data strategy and data spaces journey on AWS.

To get started, assess your workload criticality to determine whether a business-critical or non-critical configuration fits your needs. Then use the AWS Pricing Calculator to estimate costs for your specific data volumes, regions, and usage patterns. For an end-to-end reference implementation, explore the Dataspace Connector on AWS project which combines Infrastructure-as-Code with custom EDC extensions and AI tooling integration.

References

About the authors

Eclipse Dataspace Components on AWS: Architecture patterns in production

Post Syndicated from Jonas Bürkel original https://aws.amazon.com/blogs/architecture/eclipse-dataspace-components-on-aws-architecture-patterns-in-production/

Running Eclipse Dataspace Components (EDC) connectors in production on AWS requires deliberate architecture decisions around isolation, managed services, and security layering. In Part 1 of this series, we covered the fundamentals of data space architectures and EDC per the International Data Space Association’s (IDSA) standards. If you are new to EDC, we recommend starting there. We showed how connector functionality can be customized to support native integration with Amazon Web Services (AWS) Cloud services. Examples include Amazon Simple Storage Service (Amazon S3) for data storage and AWS Secrets Manager for credentials management. In this post, we dive deeper into the connector deployment architecture on AWS and present patterns and practices for production-grade deployments.

Fundamental architecture building blocks

The EDC connector consists of a control plane and a data plane that customers typically ship and deploy as containers. Depending on data integration requirements and support for specific protocols and capabilities, a custom EDC build process may need to be implemented as described in Part 1 of this series. For example, you may need OAuth 2.0 client credentials for the data plane to connect to backend systems. You store the resulting EDC container images in a container registry, such as Amazon Elastic Container Registry (Amazon ECR). Figure 1 shows an example architecture for EDC connector deployments on AWS following best practices for production use.

Architecture diagram showing production-ready EDC connector deployment on AWS with Amazon ECS, Aurora, S3, and API Gateway components

Figure 1: Production-ready EDC connector deployment on AWS

You can split the architecture into four sub-components:

  • Amazon Elastic Container Service (Amazon ECS) and AWS Fargate provide serverless container orchestration. This allows for scalable EDC deployment without managing any of the underlying infrastructure.
  • EDC requires persistence to store secrets and relational control plane data, and a means of vending OAuth 2.0 client credentials. AWS Secrets Manager, Amazon Aurora and Amazon Cognito can provide these capabilities as managed services.
  • Amazon S3 provides durable data storage for handling both inbound and outbound data that is shared and received through the data space.
  • Finally, Amazon API Gateway and Network Load Balancer provide secure, private network connectivity to EDC APIs in an isolated Amazon Virtual Private Cloud (Amazon VPC) using VPC links.

With this approach, all cloud resources belonging to a single EDC connector instance form an isolated architecture cell. You access this cell through the S3 bucket to move in data that is to be shared as part of an EDC asset, or to retrieve data received from a third party as part of an EDC data transfer. Secondly, the API Gateway can be configured to expose selected EDC API resources from its management API, data plane API and Dataspace Protocol (DSP) API. You can protect both means of interacting with the EDC architecture cell using AWS Identity and Access Management (AWS IAM) and the AWS Signature Version 4 (SigV4) protocol.

Larger enterprises participating in data spaces may decide to operate multiple EDCs depending on their requirements on failure isolation, data governance, and separation of shared and received data. A common pattern is to deploy separate connector instances per use case. Infrastructure-as-code such as AWS Cloud Development Kit (CDK) allows for automated, templatized deployment and management of EDC connectors over time while keeping operational effort at bay. Using the Dataspace Connector on AWS reference implementation, a full connector cell deploys from a single CDK command, ready to negotiate contracts and transfer data. Amazon API Gateway also comes with Model Context Protocol (MCP) proxy support. This allows EDC APIs to be consumed by authorized AI agents and MCP clients for autonomous data collection and sharing. Besides integration with agentic systems, customers often follow a workflow-based approach for connecting EDCs with their cloud-based data environments. They interact with both APIs and the peripheral S3 bucket to securely expose and retrieve external information.

Real-world validation of these architecture patterns can be seen in production deployments like the Prometheus-X Data Space Connector, for education sector use cases. This implementation uses the same core architecture we recommend: Amazon ECS with AWS Fargate for container orchestration, S3 for data storage, and event-driven processing with AWS Lambda and Amazon EventBridge. This demonstrates how these patterns work effectively in production environments across different industry sectors.

Key principles for production-readiness

We discuss some of the architecture principles that inform the best practices diagram highlighted in Figure 1 along three of the AWS Well-Architected Framework’s pillars.

Operational Excellence

Infrastructure as Code for Consistency: Define all infrastructure declaratively to support repeatable, version-controlled, and testable deployments. Automated validation, for example using CDK Nag, helps catch misconfigurations and security issues before deployment, shifting security left in the development lifecycle. The code itself serves as living documentation of the architecture.

Observability as a First-Class Concern: Treat monitoring and logging as core infrastructure components. Amazon CloudWatch Container Insights, Amazon CloudWatch Logs, and EDC’s structured health check endpoints provide visibility into system behavior, supporting proactive issue detection and faster troubleshooting. EDC APIs for health checks can be similarly exposed with restricted access through API Gateway and IAM.

Managed Services Over Self-Managed Infrastructure: Use AWS managed services (Aurora, Secrets Manager, Fargate, Cognito) instead of deploying and maintaining compatible self-managed solutions. This shifts undifferentiated heavy lifting to AWS and reduces operational burden. You gain high availability, built-in security best practices, compliance certifications, and automatic updates.

Security

Defense in Depth: Implement security through multiple independent layers rather than relying on a single control. Network isolation (VPC private subnets), security group segmentation (restricting traffic between components), IAM least privilege (scoped permissions per service), and encryption (at rest and in transit) each provide independent controls. These layers work together so that if one layer is bypassed, others continue to provide protection.

Principle of Least Privilege: Every component receives only the minimum permissions required for its specific function. Scope IAM roles to individual services (control plane, data plane) and restrict security groups to necessary ports and sources. The internal-only Network Load Balancer fronted by API Gateway prevents unintended public exposure of EDC APIs and data. This may also support security review and approval of EDC as open-source software, since APIs can be allowlisted and validated individually.

Encryption Everywhere: Encrypt data by default at every stage: at rest (Aurora, S3, Secrets Manager), in transit (TLS enforcement, HTTPS-only egress), and during processing (encrypted environment variables). This provides comprehensive data protection regardless of where information resides in the system.

Reliability

Fail Fast, Recover Automatically: Systems detect failures quickly and recover without manual intervention. ECS circuit breakers can automatically roll back failed deployments, automated health checks remove unhealthy targets, and point-in-time recovery supports rapid database restoration. This minimizes mean time to recovery (MTTR) and reduces the scope of failures, even within a single EDC architecture cell.

Design for Regional Resilience: Cross-zone load balancing distributes traffic across multiple Availability Zones (AZs), Aurora automatically replicates data across AZs, and Fargate tasks can be scheduled in any AZ. The highlighted architecture can tolerate Availability Zone failures in an AWS Region without service disruption. For more information about Availability Zones and Regions, see AWS Global Infrastructure.

Decoupled Components with Clear Boundaries: Deploy the control plane and data plane as independent services with distinct responsibilities, security contexts, and scaling characteristics. This separation enables independent updates, targeted scaling, and failure isolation between coordination logic and data transfer operations.

The remaining three Well-Architected Framework pillars of Performance Efficiency, Cost Optimization, and Sustainability are covered in the third post of this series where we discuss cost optimization strategies for running EDC connectors on AWS.

Conclusion

With the growing popularity of data spaces and EDC as a data space connector, it is important to distinguish between a setup suitable for testing and experimentation and one that is ready for production. Production environments require that business-critical processes depend on timely, successful transmission of confidential information between participants. The architecture defined in this post combines EDC deployment best practices from the community with AWS recommendations to achieve fault tolerance, scalability, and security while keeping operational complexity at a minimum.

In part 3, you will learn about cost optimization strategies to run your production-ready connector efficiently and maximize the value it returns by supporting business use cases for data sharing along your supply network. In the meantime, explore the Dataspace Connector on AWS project and see how the patterns and best practices covered in this post come together in an end-to-end reference implementation.

References

About the authors

How Generali Malaysia optimizes operations with Amazon EKS

Post Syndicated from Antoine Boucherie original https://aws.amazon.com/blogs/architecture/how-generali-malaysia-optimizes-operations-with-amazon-eks/

This post is co-authored with Ivan Amemoutou, DevOps and Cloud Lead at Generali Malaysia (“Generali”).

The insurance industry’s shift to cloud computing has accelerated the development and expansion of digital services. To support this transformation, insurers are modernizing their technology stack with solutions that enhance scalability, portability, and operational efficiency. This digital evolution is driven by growing customer expectations for seamless insurance services across all touchpoints. Generali faced this industry-wide challenge head-on, needing both to migrate their legacy applications to the cloud and meet increasing demands for new digital services. To address these needs, they embraced a modern approach by implementing containerized microservices architecture, significantly improving their operational capabilities and service delivery.

Generali started its migration to AWS in 2019. They selected Amazon Elastic Kubernetes Service (Amazon EKS) as the target container service for their modernized applications for its capabilities as an enterprise-grade container management solution and its seamless integration with other AWS services. Previous experience of the Generali DevOps and Cloud team was also a strong factor in selecting Amazon EKS. Although the selection of the target platform was straightforward, the main challenge Generali was facing was to enable the scale of adoption while maintaining a lean operational base.

Today, digital applications and several core insurance solutions are hosted on their EKS clusters, making it an important piece of infrastructure for the company. In this post, we look at how Generali is using Amazon EKS Auto Mode and its integration with other AWS services to enhance performance while reducing operational overhead, optimizing costs, and enhancing security.

Solution overview

Generali strives to implement Amazon EKS best practices and actively align their implementation with the AWS Well-Architected Framework. To that end, they follow the six pillars of Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability to build a robust and scalable platform. By applying Well-Architected principles to their EKS environment, Generali benefits from improved system resilience through automated operations and monitoring, enhanced security through AWS Identity and Access Management (IAM) integration and network policies, optimized costs through right-sizing and automatic scaling, and sustainable practices that minimize their environmental impact while maintaining high performance and reliability.

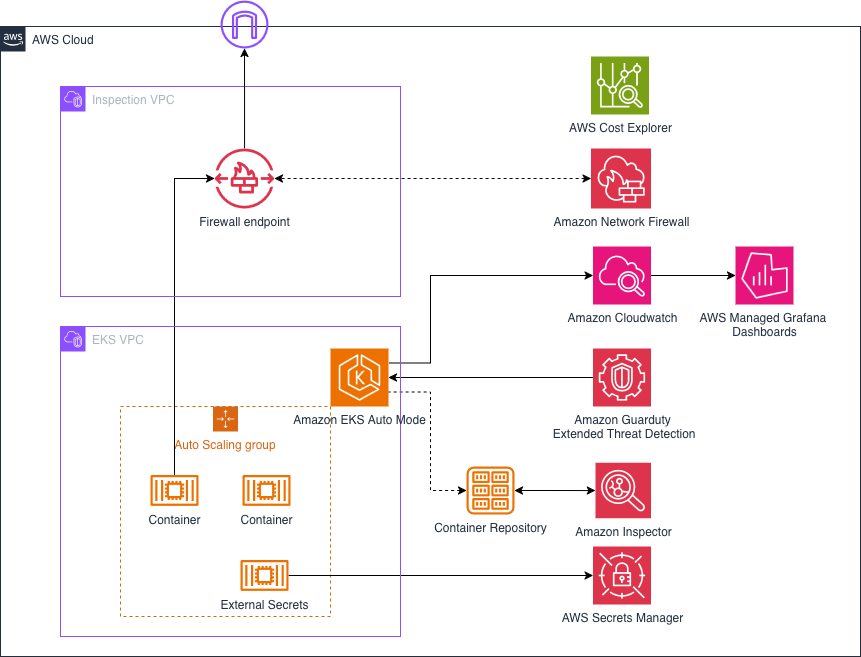
The following diagram illustrates the architecture of their EKS cluster and some of its integration points with different AWS services.AWS security and monitoring architecture diagram showing integration between Inspection VPC and EKS VPC with multiple AWS services for container workload protection and observability.

This solution offers the following benefits:

  • Simplified management of multiple containerized applications
  • Automated node provisioning and scaling
  • Enhanced security integration
  • Optimized resource utilization and simplified cost management
  • Granular multi-tenant observability

In the following sections, we discuss the integration with AWS services in more detail and how these components align with the AWS Well-Architected Framework.

Operational Excellence, Reliability, and Performance Efficiency with Amazon EKS Auto Mode

Generali faced challenges managing their expanding portfolio of containerized applications. The growth of their containerized services introduced operational inefficiencies and complexities: multiple applications from multiple tenants created operational overhead from manual orchestration and scaling to infrastructure maintenance, making it difficult to optimize costs while enforcing security and compliance across diverse application stacks. These challenges led to over-provisioning of resources and inconsistent security postures across different containerized environments.

To address these pain points, Generali has been adopting Amazon EKS Auto Mode, which automates their cluster infrastructure management, provides production-ready environments with minimal operational overhead, dynamically scales resources based on application demands, and implements consistent security practices with automated upgrades, so their teams can focus on application development rather than infrastructure complexity.

EKS Auto Mode manages the underlying nodes, load balancers, and storage configuration automatically. EKS Auto Mode takes care of scaling the cluster depending on the need of the workloads, while optimizing cost across a set of Amazon Elastic Compute Cloud (Amazon EC2) instances types selected by Generali in the node pools configuration.

With EKS Auto Mode’s expanded Shared Responsibility Model, compared to non-Auto Mode clusters, it also takes care of the patching of the underlying operating system (Bottlerocket), the different Amazon EKS add-ons installed by default, and the upgrade of the cluster, so Generali DevOps and Cloud team can focus on supporting their application teams.

While starting up EKS Auto Mode, the Generali DevOps and Cloud team had to adjust their operations to allow for those new features. For example, EKS Auto Mode releases a new version of its AMI, which automatically upgrades nodes on a regular basis, usually every week. To do so, nodes are terminated to be replaced with upgraded ones. The team had to create disruption control configurations to prevent those disruptions from impacting workloads. For example, they specified a maintenance window during off-peak hours for those upgrades. They also specified Pod Disruption Budgets and Node Disruptions Budgets to make sure critical applications would not see all the pods of a micro-service being terminated at the same time. The team can then focus on monitoring the current services and making sure they stay compliant with upcoming Amazon EKS upgrades, an activity that usually takes a fair amount of time every quarter, which is now automated with EKS Auto Mode.

Finally, the Generali DevOps and Cloud team also follow several principles to maintain reliability of their applications: they only allow stateless micro-services, they treat the underlying pods as immutable, they use Helm chart as a standardize deployment mechanism, and they use Horizontal Pod Autoscaler (HPA) to scale services based on traffic.

Security using Amazon GuardDuty, Amazon Inspector, Amazon Network Firewall, and AWS Secrets Manager

Generali implemented Amazon GuardDuty Extended Threat Detection for their EKS clusters to automatically correlate security signals across Amazon EKS audit logs, runtime behaviors, malware execution, and AWS API activity to identify sophisticated multistage attacks that traditional monitoring approaches often miss. By enabling both Amazon GuardDuty Amazon EKS protection and runtime monitoring, Generali gained comprehensive visibility into complex attack patterns such as container exploitation, privilege escalation, and unauthorized movement within their Kubernetes environment, with detailed timelines mapped to MITRE ATT&CK tactics and techniques. The benefits Generali realizes include reduced investigation time through consolidated security insights, rapid assessment of which containerized infrastructure components require immediate attention, and the ability to prioritize remediation efforts on the most critical affected resources while minimizing the potential blast radius of Amazon EKS targeted attacks.

Generali also uses the new Amazon Inspector capability to map Amazon ECR images to running containers, helping their security teams prioritize vulnerabilities based on containers currently running in their environment rather than just identifying vulnerabilities in repository images. The enhanced service provides Generali with visibility into which container images are actively running across their EKS environments, including cluster Amazon Resource Names (ARNs), the number of EKS pods where images are deployed, and last in-use dates for each vulnerability finding. The key benefits Generali realizes include the ability to prioritize remediation efforts based on actual container usage patterns rather than repository events alone, and comprehensive vulnerability management across container images.

Generali set up AWS Network Firewall to filter outbound HTTPS traffic from applications hosted on their EKS cluster by restricting outbound connections to only a set of hostnames provided by Server Name Indication (SNI) in the allow list, deploying their EKS cluster in private subnets with Network Firewall endpoints in public subnets and NAT gateways in protected subnets. The benefits Generali realizes include enhanced security through egress filtering that monitors and restricts outbound network traffic based on certificate hostnames rather than changing IP addresses, the ability to collect and analyze hostnames accessed by applications through Amazon CloudWatch alert logs for traffic pattern analysis, and improved compliance with security requirements by making sure applications can only access approved external services.

Getting secrets into pods can be done either through environment variables or as mounted volumes. Hard-coding them directly into the deployment template is not recommended, and it is better to store them in AWS Secret Manager and retrieve them dynamically. As a best practice and to reduce operational complexity, Generali choses to only host stateless containers in their cluster, alleviating the need for storage volume. To that end, the best option is to retrieve secrets dynamically and add them as environment variables to the pod. To do so, they implemented the External Secrets Operator on their EKS cluster to use Secrets Manager for centralized secret management, which reads the necessary secrets and automatically stores them as Kubernetes secrets without requiring application code changes or daemonsets. The benefits Generali realizes include improved security, management, and auditability of secret usage through centralized secret management outside their Kubernetes clusters and automatic secret synchronization on a recurring basis to capture credential rotations.

Cost Optimization using tags and Savings Plans

Although EKS Auto Mode already offers some cost optimization features, it’s important for Generali to keep track of resource consumption per business project. To that end, Generali uses AWS Billing split cost allocation data for Amazon EKS to analyze and allocate costs using the AWS Billing Console, gaining insights into Kubernetes costs alongside other AWS spend. The feature allows for split along cost allocation tags for some Kubernetes attributes. These tags include aws:eks:cluster-name, aws:eks:deployment, aws:eks:namespace, and aws:eks:node, so the company can map Amazon EKS consumption against lines of business and applications.

Generali also takes advantage of the following:

Operational Excellence and observability using custom dashboards in Amazon Managed Grafana

Hosting multiple projects from multiple business unit means that different application owners need their own custom analytics dashboards. To provide per-project granularity, Generali uses the integration between CloudWatch and Amazon Managed Grafana to create observability dashboards per EKS namespace. By connecting CloudWatch as a data source in Amazon Managed Grafana, they can visualize Amazon EKS metrics, logs, and traces through Grafana’s powerful visualization capabilities without managing the underlying Grafana infrastructure. Through this integration, Generali can create unified views of cluster health, node performance, pod resource utilization, and application performance indicators, while using Grafana’s advanced alerting and templating features for dynamic dashboard creation.

Lessons learned

Generali’s adoption of EKS Auto Mode, combined with integrated AWS security services and comprehensive observability tools, has transformed their container operations from a complex, manually managed environment to an automated, secure, and efficient platform. The integration with services like GuardDuty, Amazon CloudWatch Container Insights, and Amazon Managed Grafana has created a cohesive ecosystem that maximizes operational efficiency while minimizing management overhead. This transformation has helped the Generali DevOps and Cloud team shift its focus from infrastructure maintenance to strategic application support, resulting in improved security posture, cost optimization, and overall platform reliability.Generali realized the following key benefits:

  • Significant reduction in operational overhead with EKS Auto Mode
  • Enhanced security with automated threat detection and response
  • Reduction in infrastructure costs through optimization
  • Improved mean-time-to-resolution
  • Accelerated application deployment cycles

Conclusion

Amazon EKS Auto Mode has proven to be a transformative service for Generali, helping them build a modern, secure, and efficient container environment that aligns with AWS Well-Architected best practices. With EKS Auto Mode and its integration with AWS services like GuardDuty, Amazon Inspector, and CloudWatch, Generali created a robust foundation that not only enhances their security posture and operational efficiency but also optimizes costs. The Generali DevOps and Cloud team is now able to focus on applications teams’ support with expansion plans to host AI models and upcoming agentic applications.As organizations continue their cloud-based journey, Generali’s experience demonstrates how AWS’s comprehensive container services can help enterprises focus on innovation and business value while maintaining operational excellence, security, and cost-efficiency at scale.

If you’re interested in learning more about Amazon EKS, refer to Amazon EKS Best Practices Guide.

About Generali Malaysia

Generali Malaysia is one of the largest general insurers and an emerging life insurer in the country, dedicated to delivering best in class general and life insurance protection solutions for individuals, families, and businesses. As part of the Generali Group, a global insurance leader with over 190 years of heritage, Generali Malaysia carries forward a deep legacy of protection, service excellence, and innovation.

Today, the company is supported by more than 1,600 employees, over 9,000 agents and partners, and an extensive network of branches nationwide. Guided by its ambition to be a trusted Lifetime Partner, Generali Malaysia is committed to its purpose of empowering lives and dreams. The company continues to drive excellence by leveraging AI, data, and customer centric solutions, while embedding sustainability at the heart of its business.


About the authors

Top 10 best practices for Amazon EMR Serverless

Post Syndicated from Karthik Prabhakar original https://aws.amazon.com/blogs/big-data/top-10-best-practices-for-amazon-emr-serverless/

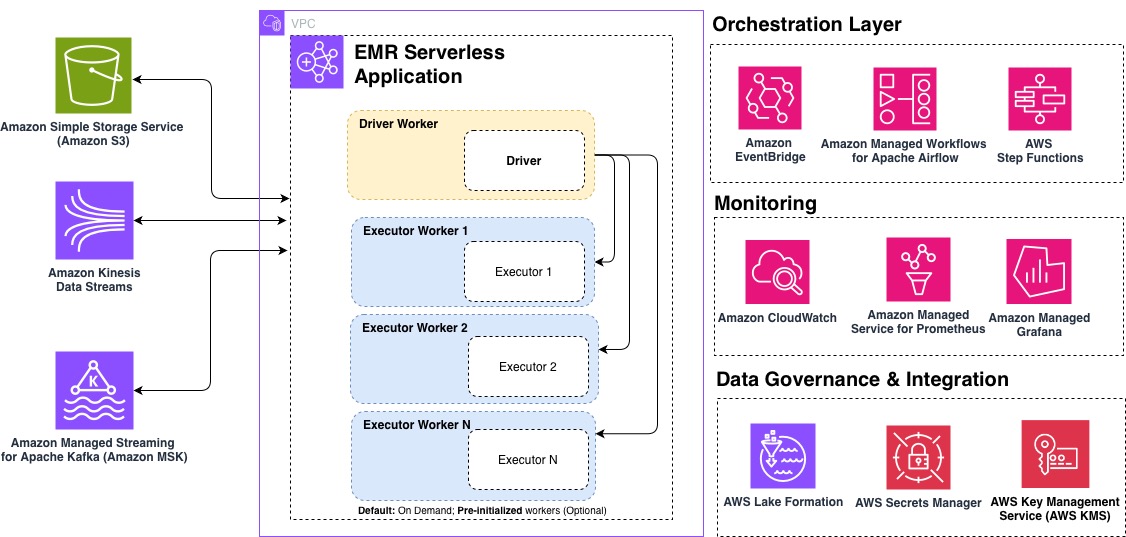
Amazon EMR Serverless is a deployment option for Amazon EMR that you can use to run open source big data analytics frameworks such as Apache Spark and Apache Hive without having to configure, manage, or scale clusters and servers. EMR Serverless integrates with Amazon Web Services (AWS) services across data storage, streaming, orchestration, monitoring, and governance to provide a comprehensive serverless analytics solution.

In this post, we share the top 10 best practices for optimizing your EMR Serverless workloads for performance, cost, and scalability. Whether you’re getting started with EMR Serverless or looking to fine-tune existing production workloads, these recommendations will help you build efficient, cost-effective data processing pipelines. The following diagram illustrates an end-to-end EMR Serverless architecture, showing how it integrates into your analytics pipelines.

1. Define applications one time, reuse multiple times

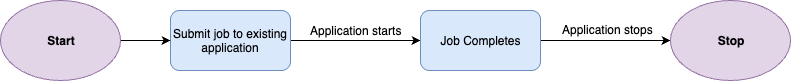
EMR Serverless applications function as cluster templates that instantiate when jobs are submitted and can process multiple jobs without being recreated. This design significantly reduces startup latency for recurring workloads and simplifies operational management.

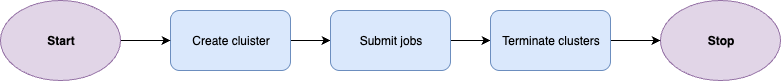
Typical workflow for EMR on EC2 transient cluster:

Typical workflow for EMR Serverless:

Applications feature a self-managing lifecycle that provisions resources to be available when needed without manual intervention. They automatically provision capacity when a job is submitted. For applications without pre-initialized capacity, resources are released immediately after job completion. For applications with pre-initialized capacity configured, those pre-initialized workers will stop after exceeding the configured idle timeout (15 minutes by default). You can adjust this timeout at the application level using AutoStopConfig configuration in the CreateApplication or UpdateApplication API. For example, if your jobs run every 30 minutes, increasing the idle timeout can eliminate startup delays between executions.

Most workloads are suited for on-demand capacity provisioning, which automatically scales resources based on your job requirements without incurring charges when idle. This approach is cost-effective and suitable for typical use cases including extract, transform, and load (ETL) workloads, batch processing jobs, and scenarios requiring maximum job resiliency.

For specific workloads with strict instant-start requirements, you can optionally configure pre-initialized capacity. Pre-initialized capacity creates a warm pool of drivers and executors that are ready to run jobs within seconds. However, this performance advantage comes with a tradeoff of added cost because pre-initialized workers incur continuous charges even when idle until the application reaches the Stopped state. Additionally, pre-initialized capacity restricts jobs to a single Availability Zone, which reduces resiliency.

Pre-initialized capacity should only be considered for:

  • Time-sensitive jobs with sub second service level agreement (SLA) requirements where startup latency is unacceptable
  • Interactive analytics where user experience depends on instant response
  • High-frequency production pipelines running every few minutes

In most other cases, on-demand capacity provides the best balance of cost, performance, and resiliency.

Beyond optimizing your applications’ use of resources, consider how you organize them across your workloads. For production workloads, use separate applications for different business domains or data sensitivity levels. This isolation improves governance and prevents resource contention between critical and noncritical jobs.

2. Choose AWS Graviton Processors for better price performance

Selecting the right underlying processor architecture can significantly impact both performance and cost. Graviton ARM-based processors offer significant performance improvement compared to x86_64.

EMR Serverless automatically updates to the latest instance generations as they become available, which means your applications benefit from the newest hardware improvements without requiring additional configuration.

To use Graviton with EMR Serverless, specify ARM64 with the architecture parameter during application creation using the CreateApplication or with the UpdateApplication API for existing applications:

aws emr-serverless create-application \
  --name my-spark-app \
  -- SPARK \
  --architecture ARM64 \
  --release-label emr-7.12.0

Considerations when using Graviton:

  • Resource availability – For large-scale workloads, consider engaging with your AWS account team to discuss capacity planning for Graviton workers.
  • Compatibility – Although many commonly used and standard libraries are compatible with Graviton (arm64) architecture, you will need to validate that third-party packages and libraries used are compatible.
  • Migration planning – Take a strategic approach to Graviton adoption. Build new applications on ARM64 architecture by default and migrate existing workloads through a phased transition plan that minimizes disruption. This structured approach will help optimize cost and performance without compromising reliability.
  • Perform benchmarks – It’s important to note that exact price performance will vary by workload. We recommend performing your own benchmarks to gauge specific results for your workload. For more details, refer to Achieve up to 27% better price-performance for Spark workloads with AWS Graviton2 on Amazon EMR Serverless.

3. Use defaults, right-size workers if needed

Workers are used to execute the tasks for your workload. While EMR Serverless defaults are optimized out of the box for a majority of use cases, you may need to right-size your workers to improve processing time and optimize cost efficiency. When submitting EMR Serverless jobs, it’s recommended to define Spark properties to configure workers, including memory size (in GB) and number of cores.

EMR Serverless configures the default worker size of 4 vCPUs, 16 GB memory, and 20 GB disk. Although this generally provides a balanced configuration for most jobs, you might want to adjust the size based on your performance requirements. Even when configuring pre-initialized workers with specific sizing, always set your Spark properties at job submission. This allows your job to use the specified worker sizing rather than default properties when it scales beyond pre-initialized capacity. When right-sizing your Spark workload, it’s important to identify the vCPU:memory ratio for your job. This ratio determines how much memory you allocate per virtual CPU core in your executors. Spark executors need both CPU and memory to process data effectively, and the optimal ratio varies based on your workload characteristics.

To get started, use the following guidance, then refine your configuration based on your specific workload requirements.

Executor configuration

The following table provides recommended executor configurations based on common workload patterns:

Workload type Ratio CPU Memory Configuration
Compute intensive 1:2 16 vCPU 32 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=32G
General purpose 1:4 16 vCPU 64 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=64G
Memory intensive 1:8 16 vCPU 108 GB spark.emr-serverless.executor.cores=16spark.emr-serverless.executor.memory=108G

Driver configuration

The following table provides recommended driver configurations based on common workload patterns:

Workload type Ratio CPU Memory Configuration
General purpose 1:4 4 vCPU 16 GB spark.emr-serverless.driver.cores=4spark.emr-serverless.driver.memory=16G
Apache Iceberg workloads 1:8(Large driver for metadata lookups) 8 vCPU 60 GB spark.emr-serverless.driver.cores=8spark.emr-serverless.driver.memory=60G

To further monitor and tune your configuration, monitor your workload’s resource consumption using Amazon CloudWatch job worker-level metrics to identify constraints. Track CPU utilization, memory usage, and disk utilization metrics, then use the following table to fine-tune your configuration based on observed bottlenecks.

Metrics observed Workload type Suggested action
1 High memory (>90%), Low CPU (<50%) Memory-bound workload Increase vCPU:memory ratio
2 High CPU (>85%), low memory (<60%) CPU-bound workload Increase vCPU count, maintain 1:4 ratio (For example, if using 8 vCPU, use 32 GB memory)
3 High storage I/O, normal CPU or memory with long shuffle operations Shuffle-intensive Enable serverless storage or shuffle-optimized disks
4 Low utilization across metrics Over-provisioned Reduce worker size or count
5 Consistent high utilization (>90%) Under-provisioned Scale up worker specifications
6 Frequent GC pauses** Memory pressure Increase memory overhead (10 –15%)

**You can identify frequent garbage collect (GC) pauses using the Spark UI under the Executors tab. There will be a GC time column that should generally be less than 10% of task time. Alternatively, the driver logs might frequently contain GC (Allocation Failure)] messages.

4. Control scaling boundary with T-shirt sizing

By default, EMR Serverless uses dynamic resource allocation (DRA), which automatically scales resources based on workload demand. EMR Serverless continuously evaluates metrics from the job to optimize for cost and speed, removing the need for you to estimate the exact number of workers required.

For cost optimization and predictable performance, you can configure an upper scaling boundary using one of the following approaches:

  1. Setting the spark.dynamicAllocation.maxExecutors parameter at the job level
  2. Setting the application-level maximum capacity

Rather than trying to fine-tune spark.dynamicAllocation.maxExecutors to an arbitrary value for each job, you can think about setting this configuration as t-shirt sizes that represent different workload profiles:

Workload size Use cases spark.dynamicAllocation.maxExecutors
Small Exploratory queries, development 50
Medium Regular ETL jobs, reports 200
Large Complex transformations, large-scale processing 500

This t-shirt sizing approach simplifies capacity planning and helps you balance performance with cost efficiency based on your workload category, rather than attempting to optimize each individual job.

For EMR Serverless releases 6.10 and above, the default value for spark.dynamicAllocation.maxExecutors is infinity, but for earlier releases, it’s 100.

EMR Serverless automatically scales workers up or down based on the workload and parallelism required at every stage of the job. This automatic scaling is continuously evaluating metrics from the job to optimize for cost and speed, which removes the need for you to estimate the number of workers that the application needs to run your workloads.

However, in some cases, if you have a predictable workload, you might want to statically set the number of executors. To do so, you can disable DRA and specify the number of executors manually:

spark.dynamicAllocation.=false
spark.executor.instances=10

5. Provision appropriate storage for EMR Serverless jobs

Understanding your storage options and sizing them appropriately can prevent job failures and optimize execution times. EMR Serverless offers multiple storage options to handle intermediate data during job execution. The storage option selected will depend on the EMR release and use case. The storage options available in EMR Serverless are:

Storage type EMR release Disk size range Use case Benefits
Serverless Storage (recommended) 7.12+ N/A (auto-scaling) Most Spark workloads, especially data-intensive workloads
  • No storage costs
  • auto-scaling
  • Reduces disk failures
  • Up to 20% cost reduction
Standard Disks 7.11 and lower 20–200 GB per worker Small to medium workloads processing datasets under 10 TB
  • Simple configuration
  • 20 GB default suitable for most workloads,
  • 200 GB max for optimal throughput
Shuffle-Optimized Disks 7.1.0+ 20–2,000 GB per worker Large-scale ETL workloads processing multi-TB
  • High IOPS and throughput
  • Up to 2 TB capacity per worker

By matching your storage configuration to your workload characteristics, you’ll enable EMR Serverless jobs to run efficiently and reliably at scale.

6. Multi-AZ out-of-the-box with built-in resiliency

EMR Serverless applications are multi-AZ from the start when pre-initialized capacity isn’t enabled. This built-in failover capability provides resilience against Availability Zone disruptions without manual intervention. A single job will operate within a single Availability Zone to prevent cross-AZ data transfer costs and subsequent jobs will be intelligently distributed across multiple AZs. If EMR Serverless determines that an AZ is impaired, it will submit new jobs to a healthy AZ, enabling your workloads to continue running despite AZ impairment.

To fully benefit from EMR Serverless multi-AZ functionality verify the following:

  • Configure a network connection to your VPC with multiple subnets across Availability Zones selected
  • Avoid pre-initialized capacity which restricts applications to a single AZ
  • Make sure there are sufficient IP addresses available in each subnet to support the scaling of workers

In addition to multi-AZ, with Amazon EMR 7.1 and higher, you can enable job resiliency, which allows your jobs to be automatically retried in case errors are encountered. If there are multiple Availability Zones configured, it will also be retried in a different AZ. You can enable this feature for both batch and streaming jobs, though retry behavior differs between the two.

Configure job resiliency by specifying a retry policy that defines the maximum number of retry attempts. For batch jobs, the default is no automatic retries (maxAttempts=1). For streaming jobs, EMR Serverless retries indefinitely with built-in thrash prevention that stops retries after five failed attempts within 1 hour. You can configure this threshold between 1–10 attempts. For more information, refer to Job resiliency.

In the event that you need to cancel your job, you can specify a grace period to allow your jobs to shut down cleanly rather than the default behavior of immediate termination. This can also include custom shutdown hooks if you need to perform custom cleanup actions.

By combining multi-AZ support, automatic job retries, and graceful shutdown periods, you create a robust foundation for EMR Serverless workloads that can tolerate interruptions and maintain data integrity without manual intervention.

7. Secure and extend connectivity with VPC integration

By default, EMR Serverless can access AWS services such as Amazon Simple Storage Service (Amazon S3), AWS Glue, Amazon CloudWatch Logs, AWS Key Management Service (AWS KMS), AWS Security Token Service (AWS STS), Amazon DynamoDB, and AWS Secrets Manager. If you want to connect to data stores within your VPC, such as Amazon Redshift or Amazon Relational Database Service (Amazon RDS), you must configure VPC access for the EMR Serverless application.

When configuring VPC access for your EMR Serverless application, keep these key considerations in mind to gain optimal performance and cost efficiency:

  • Plan for sufficient IP addresses – Each worker uses one IP address within a subnet. This includes the workers that will be launched when your job is scaling out. If there aren’t enough IP addresses, your job might not be able to scale, which could result in job failure. Verify you have adhered to best practices for subnet planning for optimal performance.
  • Set up Gateway endpoints for Amazon S3 for applications in a private subnets – Running EMR Serverless in a private subnet without VPC endpoints for Amazon S3 will route your Amazon S3 traffic through NAT gateways, resulting in additional data transfer charges. VPC endpoints for S3 will keep this traffic within your VPC, reducing costs and improving performance for Amazon S3 operations.
  • Manage AWS Config costs for network interfaces – EMR Serverless generates an elastic network interface record in AWS Config for each worker, which can accumulate costs as your workloads scale. If you don’t require AWS Config tracking for EMR Serverless network interfaces, consider using resource-based exclusions or tagging strategies to filter them out while maintaining AWS Config coverage for other resources.

For more details, refer Configuring VPC access for EMR Serverless applications.

8. Simplify job submission and dependency management

EMR Serverless supports flexible job submission through the StartJobRun API, which accepts the full spark-submit syntax. For runtime environment configuration, use the spark.emr-serverless.driverEnv and spark.executorEnv prefixes to set environment variables for driver and executor processes. This is particularly useful for passing sensitive configuration or runtime-specific settings.

For Python applications, package dependencies using virtual environments by creating a venv, packaging it as a tar.gz archive, or uploading to Amazon S3 using spark.archives with the appropriate PYSPARK_PYTHON environment variable. This allows Python dependencies to be available across driver and executor workers.

For improved control under high load, enable job concurrency and queuing (available in EMR 7.0.0+) to limit the number of jobs that can be executed concurrently. With this feature, jobs submitted that exceed the concurrency limit are queued until resources become available.

You can configure Job concurrency and queue settings using the SchedulerConfiguration property using the CreateApplication or UpdateApplication API.

--scheduler-configuration '{"maxConcurrentRuns": 5, "queueTimeoutMinutes": 30}'

9. Use EMR Serverless configurations to enforce limits

EMR Serverless automatically scales resources based on workload demand, providing optimized defaults that work well for most use cases without requiring Spark configuration tuning. To manage costs effectively, you can configure resource limits that align with your budget and performance requirements. For advanced use cases, EMR Serverless also provides configuration options so you can fine-tune resource consumption and achieve the same efficiency as cluster-based deployments. Understanding these limits helps you balance performance with cost efficiency for your jobs.

Limit type Purpose How to configure
Job-level Control resources for individual jobs spark.dynamicAllocation.maxExecutors or spark.executor.instances
Application-level Limit resources per application or business domain Set maximum capacity when creating the application or while updating.
Account-level Prevent abnormal resource spikes across all applications Auto-adjustable service quota Max concurrent vCPUs per account; request increases via Service Quotas console

These three layers of limits work together to provide flexible resource management at different scopes. For most use cases, configuring job-level limits using the t-shirt sizing approach is sufficient, while application and account-level limits provide additional guardrails for cost control.

10. Monitor with CloudWatch, Prometheus, and Grafana

Monitoring EMR Serverless workloads simplifies the process of debugging, performing cost optimization, and performance tracking. EMR Serverless offers three tiers of monitoring that work together: Amazon CloudWatch, Amazon Managed Service for Prometheus, and Amazon Managed Grafana.

  1. Amazon CloudWatchCloudWatch integration is enabled by default and publishes metrics to the AWS/EMRServerless namespace. EMR Serverless sends metrics to CloudWatch every minute at the application level, as well as job, worker-type, and capacity-allocation-type levels. Using CloudWatch, you can configure dashboards for enhanced observability into workloads or configure alarms to alert for job failures, scaling anomalies, and SLA breaches. Using CloudWatch with EMR Serverless provides insights to your workloads so you can catch issues before they impact users.
  2. Amazon Managed Service for Prometheus – With EMR Serverless release 7.1+, you can enable Prometheus for detailed Spark engine metrics to push metrics to Amazon Managed Service for Prometheus. This unlocks executor-level visibility, including memory usage, shuffle volumes, and GC pressure. You can use this to identify memory-constrained executors, detect shuffle-heavy stages, and find data skew.
  3. Amazon Managed Grafana – Grafana connects to both CloudWatch and Prometheus data sources, providing a single pane of glass for unified observability and correlation analysis. This layered approach helps you correlate infrastructure issues with application-level performance problems.

Key metrics to track:

  • Job completion times and success rates
  • Worker utilization and scaling events
  • Shuffle read/write volumes
  • Memory usage patterns

For more details, refer to Monitor Amazon EMR Serverless workers in near real time using Amazon CloudWatch.

Conclusion

In this post, we shared 10 best practices to help you maximize the value of Amazon EMR Serverless by optimizing performance, controlling costs, and maintaining reliable operations at scale. By focusing on application design, right-sized workloads, and architectural choices, you can build data processing pipelines that are both efficient and resilient.

To learn more, refer to the Getting started with EMR Serverless guide.


About the Authors

Karthik Prabhakar

Karthik Prabhakar

Karthik is a Data Processing Engines Architect for Amazon EMR at Amazon Web Services (AWS). He specializes in distributed systems architecture and query optimization, working with customers to solve complex performance challenges in large-scale data processing workloads. His focus spans engine internals, cost-optimization strategies, and architectural patterns that enable customers to run petabyte-scale analytics efficiently.

Neil Mukerje

Neil Mukerje

Neil is a Principal Product Manager at Amazon Web Services.

Amber Runnels

Amber Runnels

Amber is a Senior Analytics Specialist Solutions Architect at Amazon Web Services (AWS) specializing in big data and distributed systems. She helps customers optimize workloads within AWS data offerings to achieve a scalable, high-performing, and cost-effective architecture. Aside from technology, she’s passionate about exploring the many places and cultures this world has to offer, reading novels, and building terrariums.

Parul Saxena

Parul Saxena

Parul is a Senior Big Data Specialist Solutions Architect at Amazon Web Services (AWS). She helps customers and partners build highly optimized, scalable, and secure solutions. She specializes in Amazon EMR, Amazon Athena, and AWS Lake Formation, providing architectural guidance for complex big data workloads and assisting organizations in modernizing their architectures and migrating analytics workloads to AWS.

Know before you go – AWS re:Invent 2025 guide to Well-Architected and Cloud Optimization sessions

Post Syndicated from Anitha Selvan original https://aws.amazon.com/blogs/architecture/know-before-you-go-aws-reinvent-2025-guide-to-well-architected-and-cloud-optimization-sessions/

Are you ready to maximize your Well-Architected and Cloud Optimization learning and networking time at re:Invent 2025? We have put together this comprehensive guide to help you plan your schedule and make the most of the Well-Architected and cloud optimization sessions available this year. These sessions will deliver the practical guidance your teams need to lead strategic cloud initiatives, design next-generation architectures, optimize costs, or secure AI-powered systems.

Key themes at re:Invent for Well-Architected and Cloud Optimization – You can expect to see the following themes at re:Invent 2025

AI-powered architecture and governance

The sessions in this theme showcase how AWS is integrating AI technologies to transform traditional architectural practices. From using AI services for automated Well-Architected reviews to implementing self-evolving systems with agentic AI, these sessions demonstrate how you can use AI to automate architectural decisions, streamline governance processes, and scale best practices across the enterprise.

Sessions: ARC324-R, ARC317-R, SPS320, ARC302-R (session details are posted in the following section)

Well-Architected Framework evolution and implementation

These sessions highlight how the AWS Well-Architected Framework has evolved beyond its original scope to address modern architectural challenges. Attendees will learn how to implement the framework principles across different domains—from IoT security to backup strategies—while focusing on enterprise-scale governance and compliance.

Sessions: ARC204, SEC337, STG313-R, ARC323-R (session details are posted in the following section)

Cost optimization and FinOps

The cost optimization track focuses on innovative approaches to cloud financial management, with a strong emphasis on AI-powered FinOps solutions. Sessions range from hands-on workshops like the Frugal Architect GameDay to chalk talks on establishing effective cost governance models.

Sessions: ARC318-R, COP309-R, ARC309, DEV318 (session details are posted in the following section)

Session formats to fit your learning style

This year’s catalog features an exciting mix of content across different formats: from breakout, chalk talks, workshops, builder sessions to code talks.

Breakout sessions – Stay in the know

Sit back and enjoy these presentations to stay current with the latest solution enhancements and practical applications. AWS experts and guest speakers will share valuable insights and real-world examples.

From ideas to impact: Architecting with cloud best practices

ARC204 | Breakout session | December 1, 8:30 AM

Discover how foundational frameworks like the AWS Well-Architected Framework, AWS Cloud Adoption Framework, and AWS Cloud Operating Model evolved through customer feedback and real-world learnings from thousands of organizations, transforming from structured guidance into dynamic insights for optimizing cloud environments. Learn practical strategies for applying unified best practices to accelerate cloud transformation while managing large-scale architectural changes and maintaining operational excellence.

Build a well-architected foundation for scaling generative AI and agentic apps

AIM310 | Breakout session | December 1, 10:00 AM

Move beyond proof-of-concepts to build a production-ready foundation supporting all AI applications across your organization, addressing the critical transition from experimentation to enterprise-scale AI deployment. Navigate model access and management, tool discovery, memory and state handling, and observability at scale while building foundations that seamlessly integrate model access, orchestration workflows, agents, and tools with enterprise-grade governance controls.

AI-Powered Enterprise Architecture with ServiceNow & AWS 

ARC337-S | Breakout session | December 2, 3:00 PM

Enterprises face a core challenge: translating architectural vision into resilient cloud reality. See how integrating ServiceNow’s Enterprise Architecture Workspace with the AWS Well-Architected Tool transforms traditional design processes. Through elegant “shift-left” methodologies, architects gain contextual insights that seamlessly blend enterprise modeling with cloud best practices. This presentation is brought to you by ServiceNow, an AWS Partner.

The AI revolution in customer support: Building predictive service systems

SPS315 | Breakout session | December 3, 5:30 PM

Discover how AWS is using generative AI to transform customer support from reactive to proactive. We’ll show how large language models and AI agents are improving customer satisfaction and efficiency. Topics include smart case routing, context-aware support, early problem detection, and responsible AI use. We’ll share real results and discuss balancing AI capabilities with human touch.

Optimize AWS Costs: Developer Tools and Techniques

DEV318 | Breakout session | December 1, 3:00 PM

As cloud applications grow in complexity, optimizing costs becomes crucial for developers. This session explores AWS native tools and coding practices that reduce expenses without compromising performance or scalability.

Chalk talks

AWS speakers set the stage at the beginning of the talk and then open up for discussion. Bring your questions and dive deep into the topic with AWS experts and other customers.

Architecting agentic systems: Self-evolving patterns with AWS AI

ARC324-R | Chalk talk | December 2, 1:30 PM

Learn to architect self-evolving systems using agentic AI that align with AWS Well-Architected principles, exploring cutting-edge patterns for systems that adapt, heal, and optimize themselves autonomously while maintaining architectural integrity. Implement autonomous monitoring and self-healing capabilities with Amazon Bedrock Agents, design AI-driven security controls and automated recovery mechanisms and create systems that continuously adapt to workload patterns while maintaining reliability and performance standards.

Building Well-Architected agentic AI applications

ARC317-R/R1 | Chalk talk | December 2, 3:00 PM and December 4, 1:00 PM

Navigate generative AI agent development with robust architectural practices for security and compliance, focusing on proven patterns for building production-ready agentic AI applications that meet enterprise requirements. Design agent architectures with guardrails, monitoring systems, and access controls using the AWS Well-Architected Generative AI Lens while implementing governance patterns that ensure regulatory compliance and enable systems to scale from prototype to enterprise-wide deployment.

Using generative AI to automate architectural guidance

ARC315 | Chalk talk | December 1, 4:30 PM

Replace time-intensive manual processes with AI-powered systems that generate strategic recommendations, design principles, and best practices at scale while maintaining quality and consistency. Generate organization-specific design principles using AI analysis of architectural patterns, implement AI-driven guidance systems with effective quality control mechanisms, and build knowledge bases that feed AI-powered architectural guidance while maintaining human oversight and addressing ethical considerations.

Agentic architecting: From prototype to production-ready systems

ARC330-R/R1 | Chalk talk | December 2, 5:30PM and December 4, 2:30 PM

Transform prototypes into production-ready systems by incorporating security, monitoring, and CI/CD through agentic architecting, focusing on practical challenges of moving from experimental AI systems to production-grade architectures. Use AI agents to generate and optimize AWS CDK infrastructure and application code, implement automated security improvements and CI/CD pipeline creation, and maintain AWS Well-Architected principles while enabling teams to focus on business logic as AI handles infrastructure complexity.

AI-powered FinOps: Agent-based cloud cost management

ARC318-R/R1 | Chalk talk | December 1, 4:00 PM and December 3, 4:00 PM

Learn how intelligent agents tackle fragmented cost data and optimization processes in complex multi-account environments, moving beyond traditional FinOps approaches to autonomous, intelligent financial optimization. Architect solutions using Amazon OpenSearch Service for data aggregation and Amazon Bedrock for contextual reasoning to design secure, scalable FinOps solutions that continuously optimize costs while delivering measurable business outcomes.

Supercharge your well-architected reviews with AWS Generative AI

SPS320 | Chalk talk | December 3, 4:00 PM

Discover how Koch Industries revolutionized AWS Well-Architected reviews using generative AI, transforming weeks-long manual processes into automated, intelligent systems. Automate architectural assessments using Amazon Bedrock Knowledge Bases and Model Context Protocol (MCP) to scale best practice reviews and optimize workloads in minutes instead of days while achieving more comprehensive, consistent, and actionable recommendations through proven change management and organizational adoption strategies.

Architecting enterprise-scale governance beyond AWS Control Tower

ARC323-R/R1 | Chalk talk | December 3, 11:30 AM and December 4, 2:00PM

Discover advanced governance strategies that build upon AWS Control Tower for enterprise-scale environments requiring sophisticated compliance, security, and operational controls. Implement infrastructure across six Well-Architected Foundations capabilities with critical trade-off understanding, build efficient multi-account structures balancing security requirements with innovation needs, and architect automated compliance checks and policy enforcement at scale while enabling self-service capabilities with centralized governance and security controls.

Securing IoT Workloads with AWS IoT Lens and AWS Security Reference Architecture

SEC337 | Chalk talk | December 3, 11:30 AM

Industrial environments are reaching new levels of connectivity, automation, efficiency, and real-time data insights. However, this increased connectivity also introduces significant security challenges. Unaddressed security concerns can expose vulnerabilities and slow down companies looking to accelerate digital transformation using IoT and cloud. This chalk talk explores relevant techniques, architecture patterns, best practices and AWS security services for securing complex OT/IT environments, IoT devices, edge and cloud using the AWS Well-Architected IoT Lens and AWS Security Reference Architecture (SRA).

Establishing effective cost governance

COP309-R/R1 | Chalk talk | December 3, 3:00 PM and December 4, 12:30 PM

Generative AI agent development demands robust architectural practices for security and compliance. This chalk talk explores proven patterns for architecting secure, efficient AI agents using the AWS Well-Architected Generative AI Lens. Through collaborative discussion and whiteboarding, examine architectural governance and best practices for production environments. Learn to design agent architectures incorporating guardrails, monitoring systems, access controls, and sustainable deployment practices. Gain actionable insights for building secure, efficient, and cost-effective agentic AI applications that scale.

Break down monoliths, modernizing applications on Amazon ECS

CNS346 | Chalk talk | December 2, 4:30 PM

Join this interactive chalk talk to solve a common challenge where monolithic applications take months to deploy new features, and scaling becomes increasingly difficult. We’ll start with a real scenario, an application running on servers with a shared database. Together, we’ll design the modernization path using Amazon ECS and Well-Architected Framework principles. You’ll explore common architecture patterns, containerization strategies, CI/CD automation, and blue/green deployment approaches for ECS. After this session, you’ll walk away with a practical roadmap to transform your monolithic application into scalable microservices. Bring your curiosity and help us build the architecture live.

Hands-on workshop and Builders’ sessions

AWS speakers will introduce the use-case and tools designed to tackle the challenge. You will follow instructions, complete the tasks, and walk away with better understanding of the capabilities.

AI-powered Well-Architected reviews: Building automated governance

ARC302-R | Builders’ session | December 1, 9:00 AM; December 2, 11:30 AM and December 3, 4:00 PM

Build intelligent systems that automate AWS Well-Architected Framework reviews using generative AI, transforming manual architectural assessments into continuous, intelligent governance processes. Evaluate architecture against Well-Architected pillars while incorporating organization-specific requirements, implement continuous analysis of architecture and infrastructure as code templates, and enhance AI understanding of architectural context using Model Context Protocol servers to transform time-intensive reviews into scalable, automated processes with consistent governance.

AI-powered troubleshooting: From chaos to Well-Architected

ARC301-R | Builders’ session | December 1, 8:30 AM; December 2, 3:00 PM and December 3, 10:00 AM

Tackle complex scenarios using AI-powered tools to diagnose and resolve architectural problems, gaining practical experience using AI to transform poorly designed systems into well-architected solutions. Troubleshoot and optimize architectures with scaling bottlenecks and database inefficiencies using Amazon Q, apply Well-Architected principles to enhance performance and security under pressure, and accelerate problem identification and resolution while building AWS optimization expertise and learning to identify architectural anti-patterns before they become critical issues.

The Frugal Architect GameDay: Building cost-aware architectures

ARC309 | Workshop | December 1, 8:00 AM

Compete to implement cost efficiency improvements across multiple AWS services in this interactive GameDay, applying the Laws of the Frugal Architect to real-world scenarios for practical experience in transforming high-cost infrastructure into efficient, sustainable architectures. Address challenges spanning compute, networking, storage, serverless, and observability domains while learning to reduce cloud unit costs and improve profitability without compromising service quality through gamified scenarios that build rapid cost optimization decision-making skills.

Optimize AWS Backup using AI evaluation and Well-Architected best practices

STG313-R | Builders’ session | December 2, 1:30 PM and December 3, 8:30 AM

Enhance AWS Backup implementation using the AWS Backup Evaluator Solution, an AI agent that synthesizes data from multiple sources to provide intelligent backup optimization recommendations. Assess backup environments against the Well-Architected AWS Backup lens using Strands Agents SDK, create unified visibility across backup landscapes to identify optimization opportunities, and implement AI agents that continuously monitor backup efficiency while aligning with AWS best practices to enhance efficiency and cost-effectiveness.


Visit the AWS Cloud Support kiosk in the Venetian

Important notes:

Session dates, times, and locations listed in the post are subject to change as we continue to optimize the schedule on session popularity and venue capacity. Please check this blog post and the re:Invent session catalog regularly for the most up-to-date information about your registered sessions and newly added activities. For a full view of Well-architected content, including sessions with partners, explore the AWS re:Invent catalog and filter on the Well-Architected Framework area of interest.

Remember to reserve your seats early as popular sessions fill up quickly and bring your laptop for hands-on builders’ sessions and workshops. Register today


About the authors

Maximizing Business Value Through Strategic Cloud Optimization

Post Syndicated from Ryan Dsouza original https://aws.amazon.com/blogs/architecture/maximizing-business-value-through-strategic-cloud-optimization/

As cloud adoption continues to accelerate, organizations are realizing that the journey to the cloud is just the beginning. The real challenge—and opportunity—lies in optimizing cloud usage to drive maximum business value. At AWS, we’re committed to helping our customers navigate this journey successfully. Let’s explore some key insights and best practices for cloud optimization from the recent MIT Technology Review publication, Driving business value by optimizing the cloud.

The cloud optimization imperative

Recent data shows that global cloud infrastructure spending reached $84 billion in Q3 2024, marking a 23% year-over-year increase. This growth underscores the critical role of the cloud in driving business agility and innovation. However, to truly harness the power of the cloud, organizations must strike the right balance between cost, security, resilience, and innovation.

André Dufour, AWS Director and General Manager for AWS Cloud Optimization, emphasizes that cloud optimization involves making cloud spending efficient so that freed-up resources can be redirected to fund new innovations, such as generative AI initiatives.

Cloud optimization should be viewed as a continuous process rather than a one-time event, requiring regular assessment whenever business conditions or technical requirements change significantly. The approach should be comprehensive, addressing not just costs but all six pillars (operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability), while also recognizing that different workloads require tailored optimization strategies rather than a one-size-fits-all approach.

Best practices for success

Consider the following best practices:

  • Upskill your team – Empower your employees with cloud, cost management, and optimization skills. As Dufour notes, “Every engineer or builder plays a role in cloud optimization.”
  • Establish a cloud center of excellence – Create a centralized body responsible for developing and distributing cloud best practices throughout your organization.
  • Align finance and business – Make cloud KPIs business-centric rather than purely technical, so cloud optimization efforts support overall business goals.
  • Embrace automation – Use tools to automate cloud provisioning, monitoring, and optimization, reducing human error and effort.
  • Use AI services and solutions for efficiency – Use AI technologies to automate visualization, enhance decision-making, and optimize resource utilization.

Real-world success stories

Our customers are already seeing significant benefits from strategic cloud optimization:

  • DreamCasino achieved 30% cost savings and a 50% reduction in API response times, enabling expansion into new markets
  • BMC Software reduced cloud costs by 25% while improving security and reliability, reinvesting savings into new business opportunities
  • Even within AWS, our use of Amazon Q for application modernization saved an estimated 4,500 years of development work and $260 million in performance benefits

Business impact

Effective cloud optimization delivers more than just cost savings. It enables the following:

  • Faster innovation through reinvestment of saved resources
  • Enhanced security and operational efficiency
  • Improved ability to scale and adapt to business needs
  • Better customer experiences and faster time-to-market
  • The capability to make informed architecture and design decisions by balancing trade-offs across AWS Well-Architected pillars

AWS resources for your optimization journey

To help you accelerate your cloud optimization efforts, AWS provides several tools and resources:

Getting started

To get started, consider the following steps:

Additionally, you can engage with the AWS Cloud Optimization Success (COS) team for more detailed guidance and to help identify what to do next in your cloud optimization journey. The COS team has Solutions Architects who specialize in the Cloud Adoption Framework and Well-Architected Framework and deliver workshops and training sessions though customer and partner engagements. The team can help drive adoption of AWS services through the use of the Well-Architected and Cloud Adoption Frameworks and support other services like AWS Trusted Advisor and AWS Health to optimize cost and cloud architectures. Whether you’re just starting or looking to enhance existing implementations, the AWS COS team provides the guidance, tools, and expertise you need to succeed.

Conclusion

At AWS, we’re dedicated to helping you optimize your cloud journey. By implementing these strategies and best practices, you can unlock the full potential of the cloud, driving innovation and growth while maintaining security and operational excellence.

Ready to take your cloud optimization to the next level? Refer to the resources included in this post and contact your AWS COS team to learn how we can help you maximize the value of your cloud investments.


About the Authors

Introducing new regional implementations of Landing Zone Accelerator on AWS to support digital sovereignty

Post Syndicated from Max Peterson original https://aws.amazon.com/blogs/security/introducing-new-regional-implementations-of-landing-zone-accelerator-on-aws-to-support-digital-sovereignty/

Customers often tell me that they want a simpler path to meet the compliance and industry regulatory mandates they have in their geographic regions. In our deep engagements with partners and customers, we have learned that one of the greatest challenges for customers is the translation of security and compliance requirements into distinct technical controls. At Amazon Web Services (AWS), security is our top priority, and we understand that protecting your data in a world with changing regulations, technology, and risks takes teamwork. As we’ve said, security is foundational to sovereignty.

AWS helps organizations to develop and evolve security, identity, and compliance into key business enablers; that’s why we’re committed to working with national cyber authorities and regulators to help define and establish how their compliance standards can be translated into security best practices in the cloud. We’re responding to customer requests to create locally tailored approaches aligned to their own regional standards and guidance as established by in-region authorities.

Architectural best practice, locally tailored

Since its launch in 2022, Landing Zone Accelerator on AWS has been instrumental in helping thousands of customers deploy cloud foundations that align with multiple global compliance frameworks and AWS best practices, including the Baseline Informatiebeveiliging Overheid (BIO) in the Netherlands, and the Esquema Nacional de Seguridad (ENS) in Spain. AWS is committed to expanding our regional implementations to help customers meet specific national and regional standards and digital sovereignty goals.

In March, I was proud to share the news of the cooperation agreement between the Federal Office for Information Security (BSI) and AWS, where AWS committed to help advance digital sovereignty and cybersecurity best practices and standards in Germany and across the European Union. With that in mind, I’m excited to share that our next regional implementation of Landing Zone Accelerator on AWS will support customers with workloads in Germany. The C5-ready Landing Zone Accelerator is designed to help customers meet their Cloud Computing Compliance Criteria Catalogue (C5) compliance objectives in the cloud. This will be available to our customers in Q3-2025, and at launch, our regional implementations will also be available in AWS European Sovereign Cloud.

The C5 attestation scheme is backed by the German government and was introduced by the BSI in 2016. AWS has adhered to the C5 requirements since their inception. C5 helps organizations demonstrate operational security against common cybersecurity threats when using cloud services through the German government’s Security Recommendations for Cloud Computing Providers.

For many customers in Germany, adherence to C5 is a requirement, and this is evidenced through a compliance assessment by an authorized assessor. Preparing for this assessment is critical for a successful outcome and is why AWS has partnered with AWS Global Security & Compliance (GSCA) Partner Schellman to provide the assessor insight as to how the C5-ready Landing Zone Accelerator can accelerate and simplify the path to C5 adoption for AWS customers.

AWS Partner Schellman: Proven Track Record in C5 Assessments

As one of the few firms with deep expertise and experience in C5 assessments, Schellman has completed several dozen evaluations across a wide range of clients—from agile startups to global enterprises. This diverse portfolio underscores Schellman’s capabilities, deep technical expertise, and unwavering commitment to security assurance.

“Our team has seen firsthand how the C5 standard fosters transparency and builds trust in cloud services. We’re proud to support our clients not just in understanding C5, but in strategically leveraging it to improve security and competitiveness on a global scale.”
Jeff Schiess, Managing Director, Schellman

Lowering the Barrier to Entry – Schellman recognizes that achieving C5 compliance can sometimes be intimidating, particularly for organizations new to the framework. To that end, Schellman has performed an assessment against the foundational infrastructure provided by LZA on AWS, designed to simplify the C5 journey. The LZA provides preconfigured infrastructure templates and security baselines that significantly reduce the complexity of establishing C5-compliant cloud environments.

“With the Landing Zone Accelerator, organizations can build on a C5-ready foundation right from the start. It’s a practical, scalable solution for companies that might otherwise find the C5 standard overwhelming.”
Kristen Wilbur, Principal, Schellman

Sovereign by design

Landing Zone Accelerator on AWS automatically implements hundreds of security capabilities that map to control requirements across geographic compliance frameworks. This saves customers hundreds of hours in planning and implementing secure networking and account configurations by providing them with a foundation based on the AWS Well-Architected Security Pillar and AWS security best practices. Meeting compliance requirements, having verifiable access controls and data transfer restrictions, independence and choice over the technology stack, and surviving large-scale disruptions are some of the key capabilities that customers require of a sovereign-by-design workload. However, for many customers, translating regulatory requirements into a set of discrete technical controls and applying them consistently across one or more AWS accounts and AWS Regions can be time-intensive and challenging.

We provide customers and partners with detailed guidance on how to configure Landing Zone Accelerator on AWS in accordance with their local security and compliance requirements, including digital sovereignty requirements. This includes control mapping to local regulations or policies that shows customers how controls implemented in a landing zone are mapped to the specific requirements, calling out where customers are required to do more to meet these as part of our shared responsibility model—this includes organizational policies and procedures where customers must implement additional controls within their application or workload to meet local requirements.

Control over the location of your data

Landing Zone Accelerator on AWS provides customers with a choice of configurable preventative, detective, and proactive controls to help customers meet their data residency, security, and compliance objectives, whether you’re a public sector customer wanting to keep data in a single Region or navigating the complex needs of multi-national organizations with operations subject to differing digital sovereignty requirements.

Verifiable control over data access

Landing Zone Accelerator on AWS goes beyond just provisioning a secure, multi-account environment. It establishes a well-structured, multi-account architecture using AWS Organizations. This logically isolates workloads, management functions, and security controls into dedicated organizational units (OUs). This not only enhances security and operational efficiency, but also helps customers to enforce consistent data residency, access management, and compliance policies across their entire cloud footprint. These powerful guardrails empower customers to quickly harness the innovative potential of cloud technologies, whilst delivering business value from an established security and compliance baseline.

By providing this automated approach, AWS empowers organizations to rapidly deploy cloud environments tailored to their specific local requirements in days instead of weeks; with robust security, compliance, and operational guardrails in place from the outset. Landing Zone Accelerator on AWS is designed to simplify the path to cloud adoption and compliance for organizations, particularly those in regulated industries or with sovereignty requirements. This approach marks a shift from the previous heavy lift required for organizations to migrate workloads to the cloud while meeting their needs.

Partners at the core

There is a lot of complexity involved with navigating the evolving digital sovereignty landscape—but you don’t have to do it alone. Our AWS Digital Sovereignty Competency connects customers with trusted partners with demonstrated expertise to advise and architect for their customers’ digital sovereignty needs while taking advantage of the full potential of the AWS Cloud. As part of the competency, AWS is supporting partners to navigate customer challenges across four pillars: data residency, data protection, access control, and survivability.

Customers have told me about how challenging it can be to architect to address their sovereignty needs, often requiring manual iteration and longer time to value. Using Landing Zone Accelerator on AWS is one of the ways AWS and AWS Partners can work together to address customers’ sovereignty needs with a repeatable approach that helps our customers and partners move faster. I’m excited by how regional implementations of Landing Zone Accelerator on AWS is helping AWS Sovereignty Partners, such as Atos and SVA, to move faster without compromise.

“Compliance with regulations like C5 is essential for customers in the public sector and regulated industries, who prioritize digital sovereignty, and this is central to our Cloud for Clinics initiative with AWS in the German Healthcare market. The availability of the C5 LZA significantly reduces the technical complexity, giving us a common technical platform to build on reducing time to market. Atos is driving the operational rollout and expanding the scope of compliance mappings to further streamline customer compliance. At the same time, we are incorporating essential managed services like SOC/SIEM which we believe will make compliant cloud adoption easier to drive innovation by the Public Sector, Healthcare institutions or customers in regulated industries like Financial Services and Utilities.”
Boris Hecker, Managing Director, ATOS Germany

“Compliance with BSI C5 criteria for customers from the public sector and regulated industries is a basic requirement for the use of public cloud services. Implementing the regulations is often complex, time-consuming and resource-intensive. For this reason, customers are looking for solutions that they can tailor to the specific requirements of their industry; while ensuring they meet compliance standards. SVA supports customers in maintaining the balance between innovation and compliance with customized, C5-certified, managed services. We rely on solutions such as the Landing Zone Accelerator on AWS to reconcile the use of market-leading public cloud infrastructure with regulatory requirements.”
Patrick Glawe, Hyperscaler Lead at SVA

For more information, see Landing Zone Accelerator on AWS and AWS Digital Sovereignty Competency Partners

Max Peterson

Max Peterson

Max is the Vice President of AWS Sovereign Cloud. He leads efforts to ensure that all AWS customers around the world have the most advanced set of sovereignty controls, privacy safeguards, and security features available in the cloud. Before his current role, Max served as the VP of AWS Worldwide Public Sector (WWPS) and created and led the WWPS International Sales division, with a focus on empowering government, education, healthcare, aerospace and satellite, and nonprofit organizations to drive rapid innovation while meeting evolving compliance, security, and policy requirements. Max has over 30 years of public sector experience and served in other technology leadership roles before joining Amazon. Max has earned both a Bachelor of Arts in Finance and Master of Business Administration in Management Information Systems from the University of Maryland.

Build and operate an effective architecture review board

Post Syndicated from Darrin Weber original https://aws.amazon.com/blogs/architecture/build-and-operate-an-effective-architecture-review-board/

The rapid change of pace in computing landscapes because of cloud, artificial intelligence, and technology innovation has challenged organizations to keep up while making sure that their initiatives and projects remain compliant with enterprise guidelines and policies. An effective architecture review board (ARB) can help an organization maintain compliance with enterprise guardrails while accelerating implementation of initiatives in their project pipeline.

In this post, we identify the components of an efficient architecture review process, define what an ARB is, and describe how to build and operate an effective enterprise ARB.

What is an architecture review board?

An ARB is a multi-disciplinary team responsible for reviewing solution architectures to help ensure compliance with enterprise guidelines, best practices, and supportability. Team members include stakeholders from different disciplines throughout your organization, which typically include Security, Development, Enterprise Architecture, Infrastructure, and Operations. Including a broad set of stakeholders reduces the amount of project recycle that happens when stakeholder representation is overlooked.

An ARB isn’t a standalone group, it operates within the context of your project implementation process, reviewing solution architectures, custom development, and purchased solutions to maintain enterprise compliance and alignment with goals. As shown in the following diagram, architecture review typically occurs after the design phase—before a build or purchase decision—and again before deployment to validate that the reviewed architecture matches the solution that was built.

Project implementation process with architecture review checkpoints

Most organizations recognize the benefits and value of establishing an ARB. However, they often struggle to define and operate one in a manner that maximizes the benefits, integrates with overall project execution processes, and satisfies the needs of all the stakeholders. An efficient architecture review process imparts organizational benefits such as reduced costs, minimized security events, and diminished technical debt.

Life without a formal architecture review process

One of the most pronounced issues with implementing and maintaining software architecture is the difficulty in achieving human consensus. In any organization, you’ll find a diverse range of team members—each with their own priorities, perspectives, and pain points. Without a formalized review process, these differences can lead to prolonged debates and stalled projects. We often find that many members tend to fall into one of these personas:

The Not Invented Here The Not Invented Here – This individual doesn’t trust any software unless it was built and operated by members of their company. They’re generally wary of any cloud solution and will expend development time to avoid capital expenditure.
The Wait a Minute The Wait a Minute – This individual has good feedback and their input is welcome, but they tend to wait until the last minute before providing any feedback, making it difficult to have productive conversations and act on any constructive criticism.
The Bottleneck The Bottleneck – This individual craves control and insists that all reviews, decisions, and conversations go through them. This makes scaling the architecture review process very challenging and decisions will often come down to the whim of this one person.
The Creative The Creative – This individual has passion for software and for creating things, but will often choose complexity over simplicity and turn their architectures into art projects.
The Perfectionist The Perfectionist – This individual tends to let the perfect be the enemy of the good. While their intentions are pure, this approach can result in delayed decision making and debates on topics that might not be worth the time of the board.
The Historian The Historian – This individual has been at the company for a long time and remembers every success and failure along the way. While the context this individual brings to the table is invaluable, teams must guard against only looking to the past as they try to shape the future.

Benefits of an architecture review board

Establishing an ARB within your organization can yield substantial benefits, enhancing both the quality and efficiency of your architecture. Some key advantages are:

Improved compliance

By systematically reviewing architectural decisions, the ARB helps ensure that designs adhere to company best practices, open standards, and regulatory requirements as set forth by your enterprise architecture.

Reduced technical debt

Technical debt—taking shortcuts in the development process that lead to future complications—is a common issue in software development. The ARB helps identify and mitigate technical debt early in the design phase. By enforcing architectural standards and promoting best practices, the board helps ensure that decisions are made with long-term sustainability in mind. This approach results in more robust, maintainable codebases and reduces the likelihood of future rework.

Efficiency with lowered costs

While a formal architecture review sounds like it might have the potential for increased red tape and lowered efficiency, the ARB instead contributes to operational efficiency by standardizing architectural practices across the organization. This uniformity allows for better resource allocation, faster deployment cycles, and more predictable project timelines. By catching potential issues early in the design phase, the ARB helps avoid costly rewrites and rework, which can lead to significant cost savings over time.

Supportability

Designing for supportability is crucial for the long-term success of any application. The ARB makes sure that architectures are built with maintainability in mind, making it easier for operations teams to manage and troubleshoot systems. This focus on supportability leads to fewer downtime incidents, faster resolution times, and overall higher system reliability. By making sure the composition of the ARB crosses all parts of the organization, supportability concerns can be surfaced earlier and help ensure that changes are properly socialized.

Security

Above all, security is the most critical output of an effective ARB. The ARB plays a pivotal role in embedding security into the architectural fabric from the outset. By conducting thorough security reviews and incorporating security best practices into every design, the ARB makes sure that applications are resilient against unintended disclosure, inadvertent access, and threat actors. This proactive approach not only protects sensitive data, but also builds trust with your customers and stakeholders.

Steps for effective architecture review boards

Whether looking to establish a new architecture review process or improve the effectiveness of a current ARB, we’ve identified eight key steps to make sure that an ARB operates in a way which realizes the benefits of a robust architecture review process while maintaining enterprise compliance. With the exception of leadership support, the steps aren’t presented in a particular order and can be implemented in parallel or in whatever order fits your organization and resource availability.

Leadership support

Identifying a sponsor on the executive leadership team is crucial to the success of the ARB. An executive sponsor fosters participation from stakeholders, representing key organizations such as Security, Development, and Operations, along with gaining their commitment to the review processes. The executive sponsor helps embed the ARB function within the enterprise’s project implementation process. Supported by the executive sponsor, the ARB’s reviews serve as a formal gate within the project process, reducing attempts to bypass the review processes.

Single source for guidance, policies, and best practices

Establish a single, well-known repository or index so that the entire enterprise has a single source of truth that establishes the basis for designing and reviewing architecture. A common repository doesn’t need to be complex. It can be a central document location, wiki, or file share that’s quickly discoverable. Commonly, an enterprise’s collection of guidelines and policies are dispersed and managed by each organization using different mechanisms and repositories. Best practices are often treated as folklore passed between team members. Project teams and ARB stakeholders need to share a common understanding of the enterprise’s collective intelligence consisting of guidelines, policies, and best practices.

As the project community’s collective understanding of the enterprise guidelines and policies grows, initial solution designs are better aligned, and reviews through the ARB accelerate. After a common repository is established, consider using generative AI to create a natural language chatbot, a design chatbot, to simplify access to the collective guidelines, policies, and best practices. See Amazon Bedrock or Amazon Q – Generative AI Assistant.

Defined stakeholders

Make sure that your disciplines have defined stakeholders on the ARB. A good starting point is to identify stakeholders from the Security, Enterprise Architecture, Development, Infrastructure, and Operations teams. Broad representation on the board minimizes recycles and delays later in the project, which can occur when stakeholders aren’t engaged in the review process from the beginning. A stakeholder’s responsibility is to focus on their area of subject matter expertise and commit a portion of their time to the ARB. Consider rotating stakeholders periodically to distribute knowledge and workload through the organization.

Gated process with documented decisions

As previously described, architecture reviews typically occur after design and before solution implementation or purchase. Optionally, another architecture review takes place before deployment to validate that the solution matches what was reviewed and approved. It’s important to complete the review before implementation or the purchase decision and to get stakeholder sign off. Otherwise, projects risk rework and delay later in the process, often impacting cost or schedule to a greater degree. Document each ARB action, including approvals, reasons for recycles, exceptions required, follow-ups needed, and so on. Documented decisions should be added to the project’s overall lifecycle documentation to benefit future inspection of project or similar solution architectures.

Establish an exception process

There will always be exceptions to your enterprise guidelines or policies. Plan for exceptions with a defined process for reviewing, escalating, and gaining approval. Include leadership from both IT and business areas in the assessment and sign-off on an exception. Most importantly, set expiration dates on the exceptions–they should not be granted indefinitely. Exceptions are typically granted to accommodate a temporary nonconformance to provide time to plan for and implement a better, long-term solution.

Architecture central repository

Establish a well known, central repository for solution architecture documents. Solution documentation should be treated as living artifacts that are maintained for the lifecycle of the use case. A central architecture repository benefits teams responsible for operating and maintaining solutions, along with design teams chartered with new solution design. After a repository is established, consider including your architecture documentation in the generative AI design chatbot mentioned previously.

Automate review process

Employ automated architecture review processes wherever possible. Automated review processes allow stakeholders to focus their time on their subject matter expertise instead of administrative tasks. Consider separate review processes based on an initiative’s complexity, cost, and impact. Schedule live meetings with the ARB for the most complex and impactful solutions, and use offline mechanisms, such as email, for other efforts. Define a universal architecture template to capture areas of interest for review and automate the Q&A and sign-off processes. Consider using generative AI to do initial automated design reviews against enterprise core best practices and policies to further streamline stakeholder review processes.

Architecture review process shepherd

Identify a shepherd to help ensure that solution architectures are reviewed and the ARB review processes are broadly understood. The shepherd functions as a liaison with executive sponsors for exceptions. While the shepherd can also be a stakeholder on the board, the shepherd is not the single overall decision maker. The shepherd champions the continuous improvement of the architecture review process and mechanisms.

Conclusion

In this post, we explored the benefits of establishing an architecture review board within an organization, emphasizing its role in maintaining compliance, reducing technical debt, and enhancing operational efficiency. We discussed the challenges organizations face in setting up an effective ARB and provided guidance on the essential components and steps required to build and operate a successful ARB. By following the outlined steps, organizations can maximize the benefits of an ARB, making sure that architectural decisions align with enterprise goals and standards while fostering a culture of continuous improvement and stakeholder collaboration.

For additional guidance on garnering the leadership support necessary for an effective ARB, see Well-Architected Framework: Provide executive sponsorship. For more details on the review process, see Well-Architected Framework: The review process and AWS Well-Architected Tool, an AWS Management Console-based service that provides a consistent process for measuring your architecture using AWS best practices. If you’re interested in establishing a natural language chatbot interface for your enterprise architecture information, see Amazon Bedrock, Amazon Q Business, or Build a contextual chatbot application using Amazon Bedrock Knowledge Bases.


About the authors

Announcing the Well-Architected Data Residency with Hybrid Cloud Services Lens

Post Syndicated from Enrico Liguori original https://aws.amazon.com/blogs/architecture/announcing-the-well-architected-data-residency-with-hybrid-cloud-services-lens/

As organizations increasingly take advantage of the benefits of hybrid cloud architectures, they are often faced with the challenge of balancing data residency requirements with the flexibility of the cloud. To help you navigate this complex landscape, we are excited to introduce the AWS Well-Architected Data Residency with Hybrid Cloud Services (DRHC) Lens paper.

The AWS Well-Architected Framework provides a consistent approach for evaluating architectures and applying best practices to build reliable, secure, efficient, and cost-effective systems in the cloud. The framework is based on six pillars: Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability.

What’s in the Well-Architected Data Residency with Hybrid Cloud Services Lens?

The DRHC Lens identifies a set of key design principles to help you in the development and deployment of Well-Architected hybrid cloud workloads:

  • Classify data and workloads – Determine which data sources and workloads must remain on premises or in a specific geography to comply with data residency requirements, and which can be moved to an AWS Region.
  • Establish operational practices for data sovereignty – Develop and implement distinct processes and procedures for data and workloads that are subject to data residency or data sovereignty regulations.
  • Use in-Region services whenever possible – Data residency and data sovereignty regulations often apply only to specific elements of an application, or to specific data. For those elements that aren’t in scope for these regulations, use the broad set of services available in Regions, such as identity, automation, and monitoring services.
  • Automate infrastructure – Build orchestration and automation frameworks that adapt to data residency or data sovereignty classifications to deploy compliant, repeatable, and verifiable application stacks. Automation is critical for eliminating manual processes that might introduce mistakes that can lead to compliance failures.
  • Implement robust security measures – The protection and integrity of data is critical to complying with corporate, data-residency, and data-sovereignty regulations. Use all of the tools and services available across AWS Regions, AWS Local Zones, and on AWS Outposts, including specific preventative controls to meet data residency regualations, when developing and deploying your applications.

In addition to these design principles, the lens provides detailed guidance across the six pillars of the Well-Architected Framework:

  • Operational Excellence – Achieve effective system operations, gain operational insights, and implement continuous process improvement for hybrid cloud workloads.
  • Security – Establish control objectives, implement access controls and governance, and configure detection mechanisms to protect data across on-premises and cloud environments.
  • Reliability – Deploy multiple Outposts or Local Zones for high availability, plan for disaster recovery, and maintain operations during on-premises maintenance.
  • Performance Efficiency – Carefully select services, Regions, and configurations that align with latency, bandwidth, and data residency requirements.
  • Cost Optimization – Implement a tagging strategy, monitor and manage Outposts capacity, and optimize network configurations to reduce costs.
  • Sustainability – Anchor Outposts and Local Zones to sustainable Regions, scale infrastructure to match demand, and optimize storage to reduce energy consumption.

Who should use the DRHC Lens?

All AWS customers with data residency requirements, including government agencies, healthcare providers, financial institutions, and public sector industries who are looking for guidance on these architectural patterns, can use the DRHC Lens. When designing and maintaining your architecture with data residency in mind, the following roles can benefit from this lens:

  • Business and technology leaders — For strategic decision-making around data sovereignty requirements
  • Chief technology officers — For aligning technology choices with data residency compliance needs
  • Solutions architects and data residency specialists — For designing compliant hybrid architectures following Well-Architected principles
  • Security and compliance teams — For making sure data handling meets regulatory requirements across Regions
  • Operations teams — For maintaining daily compliance with data residency controls
  • Data engineers and edge computing specialists — For implementing technical controls that enforce data locality requirements

Conclusion

The new Well-Architected Data Residency with Hybrid Cloud Services Lens is available now. Use the lens whitepaper to adopt your hybrid cloud workloads according to the tenants of the Well-Architected Framework while maintaining data sovereignty requirements.

Applying the Data Residency with Hybrid Cloud Services Lens to your architecture helps validate your data handling practices and provides actionable recommendations to address gaps. AWS will continue to update the whitepaper as new services and features are released. Using the lens can help you consistently apply the latest patterns to meet your requirements. This allows you to deploy applications to meet your business objectives and requirements.


About the Authors

Realizing twelve-factors with the AWS Well-Architected Framework

Post Syndicated from Michael Phorn original https://aws.amazon.com/blogs/architecture/realizing-twelve-factors-with-the-aws-well-architected-framework/

Organizations that are interested in improving their development velocity that follow the principles of the twelve-factor app might find benefits in understanding how to realize those concepts on Amazon Web Services (AWS). In this post, I will help you correlate the twelve-factors app concepts as you architect solutions on AWS.

Twelve-factors

Let’s start with a quick recap of twelve-factors. The Twelve-Factor App was published in 2011 by Adam Wiggins as a collaboration between developers at Heroku. He published it at a time when developers were shifting from a paradigm of writing software-as-a-service (SaaS) applications in their own cloud environments to having the applications hosted on a cloud provider, such as AWS. Their intent was to provide “a broad set of conceptual solutions” for building applications that were portable and resilient. The principles centered around reducing the software lifecycle burden, including application introduction, maintenance and operations, through sunsetting. These principles were captured in the following 12 factors:

  1. Codebase
  2. Dependencies
  3. Config
  4. Backing services
  5. Build, release, run
  6. Processes
  7. Port binding
  8. Concurrency
  9. Disposability
  10. Development and production environment parity
  11. Logs
  12. Admin process

These principles are portable and resilient application best practices.

At AWS, we have the Well-Architected Framework to capture cloud and architecture best practices, which contains similar practices to twelve-factors. The Framework comes from years of AWS Solutions Architect collective experience of building solutions across business verticals and use cases. The results are architectures that support secure, high-performing, resilient, and cost-effective systems in the cloud. If you’re responsible for the underlying infrastructure or the application, the Framework helps you, the CTO, the architect, the developer, or operations team member, understand the benefits and trade-offs of decisions that have to be made.

A brief history of the AWS Well-Architected Framework

AWS published the first version of the Framework in 2012, and we released the AWS Well-Architected Framework whitepaper in 2015. Following the initial introduction, we added the Operational Excellence pillar in 2016 and released pillar-specific whitepapers and AWS Well-Architected Lenses in 2017. The following year, the AWS Well-Architected Tool was launched.

While twelve-factors focuses on application characteristics, the AWS Well-Architected Framework provides architectural guidance. When your architecture undergoes a Well-Architected review, you can meet the guidance for a twelve-factors application more easily. With some factors, the Framework helps the application developer delegate some responsibility from the application to the infrastructure. Both frameworks aim to help you deliver applications and services that are robust, scalable, and cloud centered. The AWS Well-Architected Framework helps you reinforce these mechanisms.

The six pillars of the AWS Well-Architected Framework

Let’s explore the six pillars of the AWS Well-Architected Framework, what each aims to achieve, and where the twelve-factors concepts intersect with AWS guidance.

The following figures shows the twelve factors and how they map to processes in AWS, which are described in this section.

1. Operational excellence

The operational excellence pillar helps you review your organization’s ability to support development and run workloads efficiently. You can use the topics in this pillar to evaluate how you operate your solutions. The pillar guides you through inspection of organizational structure, inspection of your mechanisms, and identification of obstacles and roadblocks that might slow your ability to innovate. The results include a feedback loop of continuous improvement for operating the infrastructure and solutions.

The factors you capture through operational excellence are codebase (I) and development and production environment parity (X). Codebase prescribes that there is exactly one codebase used to deploy everywhere, which echoes the purpose of reducing the operational burden of maintaining your software. The argument for a single code base is for consistency, traceability, and efficiency across a unified development lifecycle. The second factor is development and production environment parity, which encourages developers to create smaller but more frequent deployments. It also encourages developers to maintain parity not just of the core software, but also the backing services between environments. Parity of environments is conducive to smoother development and deployment processes. Additionally, this parity helps developers catch issues in a non-production environment more consistently.

AWS services that can help you achieve operational excellence are AWS CodeConnections, AWS CodePipeline, AWS CloudFormation, AWS Systems Manager, Amazon CloudWatch, AWS Config, AWS CloudTrail, Amazon EventBridge, AWS X-Ray, AWS Organizations, AWS Control Tower, AWS Trusted Advisor, AWS Service Catalog, AWS Proton, Amazon CodeGuru (Preview), AWS Lambda, Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and AWS StepFunctions

2. Security

The security pillar describes how to use AWS Cloud technologies to protect data, systems, and assets that improve your security posture. At AWS, we advocate the shared responsibility model, which applies to the security pillar. AWS is responsible for providing a secure environment for managing and operating your systems and solutions, but it is your responsibility to implement those best practices in the context of your requirements. The security pillar describes best practices such as reviewing how you manage identities for people and machines, which helps you store secrets securely.

The config (III) factor can be mapped to the security pillar, which advises you to store variables and items that depend upon the environment as environment variables. This allows you to move between deployments without having to update your code. Configuration settings such as database connection strings, API keys, credentials, and other sensitive information should be separated from the application code. At AWS, we provide services that can be used to securely meet this requirement, including AWS Secrets ManagerAWS Systems Manager Parameter Store, AWS Certificate Manager, and AWS Key Management Service (KMS).

AWS services that can help you achieve security are AWS Identity and Access Management (IAM), Amazon GuardDuty, AWS Shield, AWS Web Application Firewall (WAF), Amazon Inspector, AWS CloudHSM, Amazon Macie, AWS Security Hub, AWS Config, AWS CloudTrail, Amazon VPC (Virtual Private Cloud), AWS Direct Connect, Amazon Cognito, AWS Firewall Manager, AWS Network Firewall, and AWS IAM Access Analyzer.

3. Reliability

The reliability pillar encompasses the ability of a workload to perform its intended function correctly and consistently when it’s expected to. Reliability means that your architecture and systems:

  • Appropriately scale resources to meet demands
  • Mitigate disruptions caused by misconfiguration or transient network issues
  • Recover when disruptions do occur

Automation of scaling and recovery are best practices within the reliability pillar.

Because twelve-factors helps developers deliver a reliable application, multiple factors are categorized under the reliability pillar of the AWS Well-Architected Framework. Backing services (IV) explains that you should have flexibility for integrating services. This way, when your system experiences issues with availability, the application can replace the troubled service without code changes. You should choose the right resource that provides scalability while optimizing costs. Dependencies (III) describes that applications declare and isolate dependencies to become modular and self-contained. This speeds up recovery by simplifying the setup for handlers of the application code. Applications that adhere to the processes (VI) factor run as a collection of stateless processes to support scaling. This is equivalent to creating microservices that can scale up or down depending upon the workload or bring in additional instances when one fails. Disposability (IX) suggests that an application’s processes can be started and stopped rapidly, which makes the application resilient to failures and capable of being adapted to elastically scale.

AWS services that can help you achieve reliability are Amazon EC2 Auto Scaling, Elastic Load Balancing (ELB), Amazon RDS Multi-AZ, Amazon Simple Storage Service (Amazon S3), AWS CloudFormation, Amazon Route53, AWS Shield, AWS Backup, Amazon CloudWatch, AWS Systems Manager, AWS Global Accelerator, Amazon Aurora, AWS Lambda, Amazon DynamoDB, and AWS Transit Gateway.

4. Performance efficiency

The principles under the performance efficiency pillar focus on using computing resources to build architectures on AWS that efficiently deliver sustained performance as demand changes and technologies evolve. Topics in this pillar include simplifying the consumption of technologies that align with your goals, the ability to go global in minutes, and reducing the time and effort needed to deliver a service.

The concurrency (VIII) factor prioritizes management of processes, which should be stateless and allow for horizontal scaling, promoting performance efficiency. The backing services (IV) factor also falls under this category because it dictates flexibility in integration. This flexibility enables the application to maximize performance by using the right resource that meets scalability and performance requirements.

AWS services that can help you achieve performance efficiency are Amazon Elastic Compute Cloud (Amazon EC2), Amazon EC2 AutoScaling, Amazon Elastic Block Store (Amazon EBS), Amazon S3, Amazon Aurora, Amazon DynamoDB, Amazon ElastiCache, Amazon CloudFront,Application Auto ScalingElastic Load Balancing (ELB), AWS Lambda, Amazon API GatewayAWS Step Functions, Amazon SQS, Amazon Kinesis, AWS Global Accelerator, Amazon Aurora, AWS X-Ray, Amazon CloudWatch, and AWS Compute Optimizer.

5. Cost optimization

The cost optimization pillar provides guidance for the architecture’s ability to operate systems and deliver the business value at the lowest price point. The cost optimization reviews help you avoid unnecessary costs, analyze and attribute expenditure, and use appropriate pricing models.

The relationship of the build, release, run (V) factor advocates for the process separation and strict discipline around efficient handling of application deployments. This aligns to the cost optimization pillar because cost effective operations are typically a result of well-designed processes and mechanisms. AWS services that can support the build, release, run factor are, AWS CodeBuild and AWS CodeDeploy.

Other AWS services that can help you with cost optimization are AWS Cost Explorer, AWS Budgets, AWS Data Exports, AWS Trusted Advisor, AWS Compute Optimizer, EC2 Spot Instances, AWS Savings Plans, Amazon S3 Intelligent-Tiering, AWS Lambda, Amazon Aurora, Application Auto Scaling, AWS Organizations, AWS Resource Groups, Tag Editor, AWS Marketplace, AWS License Manager, AWS Glue, and Amazon Athena.

6. Sustainability

The sustainability pillar focuses on minimizing the environmental impact of running workloads in the cloud. Topics in this include reviewing the lifecycle of your data and retention policies as a methodology to use only what is needed.

The disposability (IX) factor is aligned to sustainability because it highlights an application’s ability to rapidly start and shut down at a moment’s notice. This provides agility and optimized use of resources during the life of the application.

AWS services that can help you achieve sustainability are AWS Customer Carbon Footprint ToolAmazon EC2 AutoScalingAWS Lambda, Amazon EC2 Spot Instances, Amazon EBS gp3 volumes, Amazon S3 Intelligent-Tiering, Amazon S3 Lifecycle configurations, AWS Graviton processors, Amazon Aurora Serverless, Amazon RDS Multi-AZ deployments, AWS Compute Optimizer, AWS Well Architected Tool, and Amazon CloudWatch.

Remaining factors

Port binding, logs, and admin processes aren’t specifically categorized into the pillars of the AWS Well-Architected Framework. However, these factors can be addressed as an essential part of the services that AWS delivers.

The seventh factor: Port binding

The port binding factor says that an application should be bound to a specific port when it’s hosted as a web application with the intention of making the application completely self-contained. In the context of AWS, we offer you different ways to achieve this principle, which are dependent upon the way your application is deployed on AWS. When implementing port binding on AWS, we offer features such as security, service discovery, and dynamic port mapping to simplify and secure your applications through services like Amazon EC2, Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), AWS Elastic Beanstalk, AWS App Runner.

The eleventh factor: Logs

The logs factor dictates that an application should treat its running process as an event stream out to files that are managed completely by the execution environment. AWS offers many types of logging to capture different aspects of your application and the supporting infrastructure. CloudWatch is a centralized logging management service that monitors, stores, and provides access to log files from AWS services. For more detail, see AWS services for logging and monitoring.

The twelfth factor: Admin processes

The admin processes factor advises application developers to perform administrative tasks in an isolated manner to minimize the impact on the main application. At AWS, this factor is realized as a separation of the control plane and the data plane. The control plane is responsible for managing, configuring, and controlling the network or system infrastructure, while the data plane is responsible for the handling the actual user data or traffic. This separation is an inherent part of AWS services. We believe this separation allows AWS to deliver services that are scalable, highly available, secure, and efficient.

Applying the AWS Well-Architected Framework

The Framework shouldn’t be treated as a checklist that you review after development is complete. Instead, a review should be explored during the design phase to help you learn and apply architectural best practices. By the end of development, architects should have built a solution that facilitates faster, lower-risk service building and deployment. The Framework is not a static document, and as AWS evolves, architects continue to learn from working with customers and refine the definition of well-architected.

Conclusion

If you are familiar with twelve-factors or want to develop a twelve-factors app on AWS, read more about the AWS Well-Architected Framework. Consider starting a review project on your own to explore the detailed questions underneath each category or if you have specific workload that you’re already working on. You can use one of the many AWS Well-Architected Tool lenses to focus on applying these best practices to the services that you’re using. To get started on a lens review, see AWS Well-Architected Tool, which is accessible at no charge through the AWS Management Console.


About the author

Top Architecture Blog Posts of 2024

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2024/

Well, it’s been another historic year! We’ve watched in awe as the use of real-world generative AI has changed the tech landscape, and while we at the Architecture Blog happily participated, we also made every effort to stay true to our channel’s original scope, and your readership this last year has proven that decision was the right one.

AI/ML carries itself in the top posts this year, but we’re also happy to see that foundational topics like resiliency and cost optimization are still of great interest to our audience.

(By the way, if you were hoping for more AI/ML content, head on over to our sister channel, the AWS Machine Learning Blog!).

Without further ado, here are our top posts from 2024!

#10 Deploy Stable Diffusion ComfyUI on AWS elastically and efficiently

This post helps you get started using ComfyUI, and was so successful that we followed it up later in the year with How to build custom nodes workflow with ComfyUI on EKS!

Architecture for deploying stable diffusion on ComfyUI

Figure 1. Architecture for deploying stable diffusion on ComfyUI

#9 Let’s Architect! Designing Well-Architected systems

In keeping with Let’s Architect! series, we have our first of three favorites for the year. This set of resources helps you apply Well-Architected standards in practice.

Let's Architect

Figure 2. Let’s Architect

#8 Let’s Architect! Learn About Machine Learning on AWS

As I said, Let’s Architect! has a winning series, and they’ve got a finger on the pulse of the tech world. This post about machine learning showcases some of the most exciting things happening at AWS.

Let's Architect

Figure 3. Let’s Architect

If you’re more interested in generative AI, you can also take a look at another post from 2024: Let’s Architect! GenAI

#7 Creating an organizational multi-Region failover strategy

Preparedness is another common theme in this year’s favorites. Michael, John, and Saurabh are well-versed in multi-Region architecture, and they’re here to share some strategies to contain failure impact.

When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

Figure 4. When the application experiences an impairment using S3 resources in the primary Region, it fails over to use an S3 bucket in the secondary Region.

#6 Building a three-tier architecture on a budget

Let’s talk cost optimization. This post about a three-tier architecture that relies on the AWS Free Tier is a must-read for anyone looking for tips to help them avoid unnecessary costs (and that’s everyone).

Example of a three-tier architecture on AWS

Figure 5. Example of a three-tier architecture on AWS

#5 Announcing updates to the AWS Well-Architected Framework guidance

As usual, Haleh & team are pros at making sure the Well-Architected Framework is current and relevant. Take a look at the enhanced and expanded guidance in all six pillars.

Well-Architected logo

Figure 6. Well-Architected logo

#4 Let’s Architect! Serverless developer experience in AWS

One more winning post from Luca, Federica, Vittorio, and Zamira! This collection of developer resources includes new ideas in AWS Lambda, Amazon Q Developer, and Amazon DynamoDB.

Let's Architect

Figure 7. Let’s Architect

#3 London Stock Exchange Group uses chaos engineering on AWS to improve resilience

This post from April 1 was not an April Fool’s joke! See how LSEG designed failure scenarios to test their resilience and observability.

Chaos engineering pattern for hybrid architecture (3-tier application)

Figure 8. Chaos engineering pattern for hybrid architecture (3-tier application)

#2 Achieving Frugal Architecture using the AWS Well-Architected Framework Guidance

Frugality AND Well-Architected? What a winning combo! This post, inspired by the 2023 re:Invent keynote, outlines the seven laws of Frugal Architecture.

Well-Architected logo

Figure 9. Well-Architected logo

#1 How an insurance company implements disaster recovery of 3-tier applications

And finally, our number one post of the year! Amit and Luiz showcase a customer solution with real-world applications that builds on the guidelines of other posts in this list! Well done!

The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Figure 10. The Pilot Light scenario for a 3-tier application that has application servers and a database deployed in two Regions

Thank you!

As always, thanks to our contributors for their dedication and desire to share, and to you, our readers! We would be nothing with you. Literally.

For other top post lists, see our Top 10 and Top 5 posts from previous years.

Announcing updates to the AWS Well-Architected Framework guidance

Post Syndicated from Haleh Najafzadeh original https://aws.amazon.com/blogs/architecture/announcing-updates-to-the-aws-well-architected-framework-guidance-3/

We are excited to announce the availability of enhanced and expanded guidance for the AWS Well-Architected Framework with the following six pillars: Operational ExcellenceSecurityReliabilityPerformance EfficiencyCost Optimization, and Sustainability

This release includes new best practices and improved prescriptive implementation guidance for the existing best practices. This includes enhanced recommendations and steps on reusable architecture patterns focused on specific business outcomes.

A brief history

The Well-Architected Framework is a collection of best practices that allow customers to evaluate and improve the design, implementation, and operations of their workloads in the cloud.

2024 AWS Well-Architected guidance timeline

Figure 1. 2024 AWS Well-Architected guidance timeline

In 2012, we published the first version of the Framework. In 2015, we released the AWS Well-Architected Framework whitepaper. We added the Operational Excellence pillar in 2016. We released the pillar-specific whitepapers and AWS Well-Architected Lenses in 2017. The following year, the AWS Well-Architected Tool was launched.

In 2020, we released the new version of the Well-Architected Framework guidance, more lenses, and an API integration with the AWS Well-Architected Tool. We added the sixth pillar, Sustainability in 2021. In 2022, dedicated pages were introduced for each consolidated best practices across all six pillars, with several best practices updated with improved prescriptive guidance. By December 2023, we improved more than 75% of the Framework’s best practices. As of November 2024, we’ve refreshed 100% of the Framework’s best practices at least once since October 2022.

What’s new

The Well-Architected Framework supports customers as they mature in their cloud journey by providing guidance to help achieve more operable, secure, sustainable, scalable, and resilient environment and workload solutions.

The content updates and prescriptive guidance improvements in this release provide more complete coverage across AWS, helping customers make informed decisions when developing implementation plans. We added or expanded on guidance for the following services in this update: Amazon API Gateway, Amazon CloudFront, Amazon CloudWatch, Amazon CodeGuru, Amazon Cognito, Amazon GuardDuty, Amazon Inspector, Amazon Macie, Amazon Q Business, Amazon Q Developers, Amazon Redshift, Amazon S3, AWS Certificate Manager, AWS CloudFormation, AWS CloudTrail, AWS CodeBuild, AWS CodeDeploy, AWS CodePipeline, AWS Config, AWS Control Tower, AWS Customer Carbon Footprint Tool, AWS Glue, AWS Health, AWS Identity and Access Management (IAM), AWS Key Management Service (KMS), AWS OpenSearch, AWS Organizations, AWS Resource Access Manager, AWS Secrets Manager, AWS Security Hub, AWS Step Functions, AWS Systems Manager, AWS Trusted Advisor, AWS Verified Access, and AWS WAF.

Pillar updates

Operational Excellence

In the Operational Excellence Pillar, we updated five best practices across four questions. This includes OPS02, OPS05, OPS09, and OPS10. The updates in this release include improved prescriptive guidance on multiple AWS services. OPS02-BP02 updates leverage Amazon Q Business for improving workforce collaboration and productivity. OPS05-BP08 updates demonstrate AWS Organizations and AWS Control Tower capabilities that enable updates to a multi-environment setup while meeting governance and policy requirements. OPS09-BP01 and OPS09-BP02 have updated guidance and resources for developing operational key performance indicators (KPIs). OPS10-BP02 has been updated with information on AWS Health, including its planned lifecycle events feature, for integrating into an incident management workflow.

Security

In the Security Pillar, we updated 43 best practices across nine questions. This includes SEC02, SEC03, SEC04, SEC06, SEC07, SEC08, SEC09, SEC10, and SEC11. All best practices in SEC03 (Permissions management) were revised, with updates to guidance on Attribute Based Access Control (ABAC), AWS IAM Access Analyzer, and emergency access processes. SEC02 (Identity management) also saw updates to all six of its best practices, including refinements to guidance on identity federation and secrets management. SEC07 through SEC11 received updates to guidance on data protection, incident response, and application security. Key updates include replacing the security information and event management SIEM solution on AWS OpenSearch recommendation with AWS CloudTrail Lake in SEC04 (Detection), expanded guidance on AWS S3 Object Lock and AWS S3 Glacier Vault Lock in SEC08 (Protecting data at rest), and the addition of recommendations for Mutual Transport Layer Security (mTLS) and private certificates in SEC09 (Protecting data in transit). Overall, these changes reflect AWS’s commitment to providing up-to-date, comprehensive security guidance in line with evolving best practices and new service capabilities.

Reliability

In the Reliability Pillar, we updated 14 best practices across nine questions. This includes REL01, REL02, REL04, REL06, REL07, REL08, REL10, REL12, and REL13. We expanded and clarified our guidance throughout the Pillar and added detailed implementation steps to each best practice that did not previously have them. We refreshed our multi-location deployment guidance by merging REL10-BP02 into REL10-BP01, while improving the prescriptive guidance of this best practice with a new title of Deploy the workload to multiple locations. We updated our idempotent operations guidance in REL04-BP04 to provide detailed technical guidance for builders who wish to provide idempotent APIs and updated the title to Make mutating operations idempotent. We merged functional testing guidance by migrating the content previously published under REL12-BP03 to REL08-BP02 (Integrate functional testing as part of your deployment) and expanded our guidance on testing in CI/CD pipelines. We refreshed REL07-BP01 to emphasize infrastructure as code (IaC) as a cornerstone of automated resource management and scaling. We improved our guidance in REL06-BP02 on how to use system and application logs to improve workload observability. We also refreshed our links to relevant resources including documents, videos, and presentations.

Performance Efficiency

In the Performance Efficiency Pillar, we updated the resources of PERF03-BP04 with the latest services.

Sustainability

In the Sustainability Pillar, we updated 10 best practices across six questions. This includes SUS01, SUS03, SUS04, SUS05, and SUS06. Best practices SUS01-BP01, SUS03-BP02, SUS03-BP05, SUS04-BP03, SUS04-BP05, SUS04-BP06, SUS04-BP07, SUS04-BP08, SUS05-BP04, and SUS06-BP02 now offer improved prescriptive guidance. Additionally, we added a new best practice, SUS06-BP01 Communicate and cascade your sustainability goals, which highlights the critical role of the central IT team in cascading sustainability goals and objectives across the broader organization. By strategically leveraging the cloud, implementing resource-efficient practices, and employing sustainability-focused tools and analytics, IT teams can play a pivotal role in driving meaningful reductions in the organization’s environmental impact.

Conclusion

This release includes updates and improvements to the Framework guidance totaling 78 best practices. As of this release, we’ve updated 100% of the existing Framework best practices at least once since October 2022. With this release, we have refreshed 100% of all the pillars of the Framework including the Reliability Pillar, with 14 of its best practice updated for the first time since major Framework improvements started in 2022.

Updates in this release will be incorporated into the AWS Well-Architected Tool in future releases, which you can use to review your workloads, address important design considerations, and help you follow the AWS Well-Architected Framework guidance.

The content will be available in 11 languages: English, Spanish, French, German, Italian, Japanese, Korean, Indonesian, Brazilian Portuguese, Simplified Chinese, and Traditional Chinese.

Ready to get started? Review the updated AWS Well-Architected Framework Pillar best practices and pillar-specific whitepapers.

Have questions about some of the new best practices or most recent updates? Join our growing community on AWS re:Post.

Let’s Architect! Building multi-tenant SaaS systems

Post Syndicated from Luca Mezzalira original https://aws.amazon.com/blogs/architecture/lets-architect-building-multi-tenant-saas-systems/

Software as a Service (SaaS) applications offer a transformative solution for businesses worldwide, delivering on-demand software solutions to a global audience. However, building a successful SaaS platform demands on meticulous architectural planning, especially given the inherent challenges of multi-tenancy. It’s also essential to ensure that each tenant’s data remains isolated and protected from unauthorized access and that multi-tenant systems are cost-optimized and can sustain the scaling of the SaaS business provider.

In this blog post, we will explore some of the key elements and best practices for designing and deploying secure and efficient SaaS systems on AWS.

Building cost-optimized multi-tenant SaaS architectures

Cost is a key factor to consider when we design new systems. Multi-tenancy requires teams to think beyond the basics of auto scaling, adopting strategies to allow their architecture to support a complex cost-scaling challenges. In this session, the speaker covers some design patterns for distributed systems to support the continually evolving scale needs of the environment, while optimizing the cost of the infrastructure.

The architectural model chosen for deploying multi-tenant systems—pooled, siloed, or mixed—significantly influences the cost optimization strategy. Each approach offers distinct trade-offs in terms of resource allocation, scalability, and cost efficiency.

Figure 1. The architectural model chosen for deploying multi-tenant systems—pooled, siloed, or mixed—significantly influences the cost-optimization strategy. Each approach offers distinct trade-offs in terms of resource allocation, scalability, and cost efficiency.

Take me to this video

Well-Architected SaaS Lens

The SaaS Lens for the AWS Well-Architected Framework empowers customers to assess and enhance their cloud-based architectures, fostering a deeper understanding of the business implications of their design choices. By bringing together technical leadership and diverse teams to discuss strategies for improving various aspects of the system, the AWS Well-Architected Framework facilitates collaborative decision-making. Moreover, the AWS account team can provide valuable support in conducting these assessments, offering expert guidance and insights. The AWS SaaS Lens specifically focuses on how to design, deploy, and architect multi-tenant SaaS application workloads within the AWS Cloud.

The microservices running in a multi-tenant environment must be able to reference and apply tenant context within each service. At the same time, it’s also our goal to limit the degree to which developers need to introduce any tenant awareness into their code.

Figure 2. The microservices running in a multi-tenant environment must be able to reference and apply tenant context within each service. At the same time, it’s also our goal to limit the degree to which developers need to introduce any tenant awareness into their code.

Take me to this well-architected framework

SaaS anywhere: Designing distributed multi-tenant architectures

Not every SaaS provider has the luxury of running all the moving parts of their solution within their own infrastructure. SaaS teams might support a range of diverse system models, where architectures might include customer-hosted data, edge deployment for parts of the application, and on-premises components. In this session, you can learn the strategies to support the complexities of this distributed model without undermining the resilience, operational efficiency, and agility goals of your solution. The video covers how this influences the onboarding, deployment, and profile management of the SaaS environment.

In this architectural pattern, tenants are demanding to have the ML workload in their environment. So, the SaaS provider only manages the SaaS Control plane where tenants deploy the application plane in their environment, including the ML workload and the necessary components around it.

Figure 3. In this architectural pattern, tenants are demanding to have the ML workload in their environment. So, the SaaS provider only manages the SaaS control plane where tenants deploy the application plane in their environment, including the ML workload and the necessary components around it.

Take me to this video

Deploying multi-tenant SaaS applications on Amazon ECS and AWS Fargate

Containers are frequently employed in multi-tenant SaaS environments to enhance scalability, isolation, and resource efficiency. Developing such systems requires addressing multiple challenges, including tenant isolation, tenant on-boarding, tenant-specific metering, monitoring, and other factors related to multi-tenancy. This session explores how to effectively manage all of these aspects when deploying solutions on AWS Fargate.

Microservices architecture can enhance security isolation by dividing applications into smaller, independent services, reducing the potential impact of a breach.

Figure 4. Microservices architecture can enhance security isolation by dividing applications into smaller, independent services, reducing the potential impact of a breach.

Take me to this video

AWS Serverless SaaS Workshop

Serverless helps to create multi-tenant architectures thanks to services like AWS Lambda that isolate your business logic per request, making them the perfect companion to run a SaaS platform. This workshop provides a hands-on introduction to creating serverless multi-tenant SaaS applications, helping you get started and gain practical experience.

This is the high level architecture of the web application you will use in the AWS Serverless SaaS Workshop. In the labs, you will use this web application to add features that are needed to build this final SaaS application.

Figure 5. This is the high-level architecture of the web application you will use in the AWS Serverless SaaS Workshop. In the labs, you will use this web application to add features that are needed to build this final SaaS application.

Take me to this workshop

See you next time!

Thanks for reading! Multi-tenant SaaS architectures require a careful design of your system. In this post, you have discovered key elements for properly designing your next SaaS workloads. In the next blog, we will talk about modern data architectures.

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

Achieving Frugal Architecture using the AWS Well-Architected Framework guidance

Post Syndicated from Ashley DeLoach original https://aws.amazon.com/blogs/architecture/achieving-frugal-architecture-using-the-aws-well-architected-framework-guidance/

As part of the re:Invent 2023 keynote, Dr. Werner Vogels introduced the Frugal Architect mindset. This mindset emphasizes the importance of continuous learning, curiosity, and regular revision of architectural choices with a focus on cost and sustainability. Cost and sustainability should be treated as critical non-functional requirements, alongside factors like security, compliance, and performance. The Frugal Architect approach involves measuring and optimizing cost at every stage of the development process, which allows for innovation in parallel with promoting responsible resource usage. In the rapidly-evolving technology landscape, builders should adopt the Frugal Architect mindset to balance innovation with cost efficiency and environmental sustainability.

This blog discusses how the six pillars of the AWS Well-Architected Framework (operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability) align with the seven Frugal Architect laws. It demonstrates how adhering to the principles and best practices outlined in these pillars can help architects and builders effectively implement the Frugal Architect laws in their projects. The Well-Architected Framework provides a comprehensive set of guidelines that embed the concepts of frugality, efficiency, and cost effectiveness, which are the core tenets of the Frugal Architect laws. By following the Framework’s pillars, architects can build secure, reliable, efficient, and cost-optimized systems and promote sustainability.

Make Cost a Non-functional Requirement (Law 1)

Non-functional requirements are criteria that evaluate a system’s operation instead of its specific features or functionality. This includes aspects like accessibility, availability, scalability, security, portability, maintainability, and compliance. However, one crucial non-functional requirement that is often overlooked is cost. Consider implications early on and throughout the design, development, and operation of your systems. Organizations can strike a balance between desired features, time-to-market, and operational efficiency through early prioritization of cost considerations. The Frugal Architect argues that you should treat cost as a fundamental non-functional requirement that should be given upfront consideration when planning and initiating system development projects.

The Cost Optimization Pillar of the AWS Well-Architected Framework provides guidance on how to optimize costs when using AWS Cloud services. It emphasizes treating cost as a key requirement, not an afterthought. The main principles focus on the importance of a robust financial management processes, adoption of a cloud consumption model that allows for flexible scaling and pay-per-use billing, continual measurement of outputs against costs to optimize efficiency, use of managed services to minimize operational overhead, and implementation of transparent cost attribution to tie cloud spending to revenue sources and workloads. Organizations that follow these practices can effectively manage and optimize their costs and benefit from the scalability and agility of cloud computing.

These cost optimization principles can help organizations maximize the financial benefits of using the AWS Cloud and avoid wasteful spending. Cost optimization is an ongoing process that includes rightsizing, higher output for the same cost, and use of the most cost-effective AWS services. The pillar promotes a disciplined approach to evaluate trade-offs between cost and other optimization areas like performance or reliability. Overall, you can use this pillar to make informed decisions to provision and operate AWS services cost-effectively.

Systems that Last Align Cost to Business (Law 2)

The durability and longevity of a system are closely tied to how well its costs align with the underlying business model. During the creation of a system, consider revenue sources and profit drivers. The key is to identify the primary dimension or aspect that generates revenue, and then verify that the system architecture supports and optimizes for that revenue-generating dimension. Essentially, revenue and profitability considerations should be the primary forces behind cost decisions in system design.

The AWS Well-Architected Cost Optimization Pillar provides practices and guidance for organizations to accurately monitor their AWS costs and usage. This visibility helps users understand the profitability of different business units and products, which facilitates informed decisions on resource allocation across the organization. Organizations can implement these practices to gain insights into their AWS spending patterns, which aids in development of effective cost optimization strategies. Overall, accurate expenditure analysis and attribution are crucial for organizations to optimize cloud costs, measure ROI, and make data-driven resource allocation decisions.

It’s important to accurately identify and attribute cloud costs to specific workloads. The cloud allows for transparent cost attribution, which helps organizations link costs to individual revenue streams and workload owners. This granular cost attribution data empowers workload owners to measure return on investment (ROI) for their workloads. With detailed cost information, workload owners can optimize resource utilization and reduce costs by rightsizing resources, eliminating waste, and making informed decisions. Organizations must use accurate cost attribution to understand where their cloud spending is going and verify that resources are being used efficiently across different workloads and revenue streams.

Architecting is a Series of Trade-Offs (Law 3)

Architectural decisions involve trade-offs, particularly between cost, resilience, and performance. Systems will inevitably fail, so investment in resilience is important but may impact performance. It’s important to find the right balance between technical requirements and business needs and align with risk tolerance and budget constraints. Frugality is about maximizing value, not just minimizing spend. Frugality means that you determine what you’re can pay for based on your priorities and make informed trade-off decisions. Ultimately, architectural choices require careful consideration of the tensions between different non-functional requirements.

The AWS Well-Architected Framework helps you make architectural trade-offs through its design principles and practices across its six pillars with your business requirements in mind. As you architect workloads, you make trade-offs between pillars based on your business context. You might optimize to improve the sustainability impact and reduce cost at the expense of reliability in development environments, or for mission-critical solutions. You might optimize reliability with increased costs and sustainability impact. In ecommerce solutions, performance can affect revenue and customer propensity to buy. Security generally is not a viable trade-off against the other pillars.

Rather than optimizing for any single pillar, the Framework guides a holistic evaluation across all pillars to determine the right architectural approach. Organizations can use AWS best practices while they find the optimal balance that aligns with their unique requirements. The key is making intentional trade-off decisions instead of following any uniform approach.

Unobserved Systems Lead to Unknown Costs (Law 4)

Without proper observation and measurement, the true operational costs of a system remain hidden, and wasteful practices can persist unnoticed. Just as exposing a utility meter prompts more mindful usage, visibility increases into costs can drive more sustainable behaviors. While implementing comprehensive monitoring requires upfront investment, the long-term benefits of conserving resources and optimizing efficiency make it a worthwhile endeavor. Ultimately, you should maintain cost awareness to foster a culture of responsible, sustainable practices.

The Operational Excellence Pillar of the AWS Well-Architected Framework emphasizes the importance of observability to gain actionable insights into workloads. This involves creation of key performance indicators (KPIs) and use of observability data telemetry to comprehensively understand workload behavior, performance, reliability, cost, and health. Organizations can implement observability best practices to make informed decisions and take prompt action when business outcomes are at risk due to issues with workload operation. Observability data provides visibility into the current state and helps identify areas for improvement. This means that organizations can be proactive in performance optimization, reliability enhancement, and cost reduction based on the actionable insights derived from observability telemetry data. Overall, observability is crucial for maintenance of operational excellence through the use of data-driven decision-making and continuous improvement of workloads.

Overall, monitoring guidance is a core component across multiple pillars of the Well-Architected Framework, as it helps organizations effectively manage and optimize their cloud workloads. For more detail on the monitoring principles of the AWS Well-Architected Framework, see Cost-Aware Architectures Implement Cost Controls (Law 5).

Cost-Aware Architectures Implement Cost Controls (Law 5)

The key aspects of frugal architecture combine granular controls with robust monitoring to identify areas for optimization. This helps you optimize costs and maintain a good user experience. With a robust monitoring system, you can take action where improvements are needed.

The AWS Well-Architected Framework aligns with the concept of frugality, which focuses on maximizing value rather than just minimizing spending. The Framework helps businesses achieve maximum value by making architectural choices that meet their specific requirements.

The Cost Optimization Pillar emphasizes the continual monitoring of usage and costs to identify opportunities for efficiency improvements and cost savings. This includes expenditure analysis, adoption of consumption-based models, and implementation of cloud financial management practices.

The Security Pillar, Reliability Pillar, and Performance Efficiency Pillar reinforce the importance of monitoring systems, workloads, and costs in real-time to maintain security, automatically recover from failures, and optimize performance relative to cost.

The Sustainability Pillar focuses on measurement of a workload’s current and forecasted environmental impact. It recommends continual evaluation of new hardware and software offerings that can reduce the environmental footprint.

Overall, monitoring guidance spans multiple Well-Architected pillars to maximize value through optimization of cost, performance, security, reliability, and sustainability.

Cost Optimization is Incremental (Law 6)

Cost efficiency is a continuous process, not a one-time goal. Regularly monitor your systems to identify inefficient patterns and areas for optimization. Revisit and refine systems periodically to find additional opportunities for improvement and further reduce costs over time.

The Cost Optimization Pillar covers principles like analysis and attribution of expenditure, measurement of overall efficiency, adoption of a consumption model, and implementation of cloud financial management practices.

Additionally, the Operational Excellence Pillar provides principles that apply not just to cost optimization but all pillars. These include observability for actionable insights, safe automation where possible, frequent small reversible changes, frequent refinement of operations procedures, anticipation of failure, and documentation and distribution of learning from operational events and metrics.

Organizations can follow these AWS Well-Architected Framework principles and their practices to continuously improve their cloud architectures and operations and optimize costs effectively.

Unchallenged Success Leads to Assumptions (Law 7)

We should continue to reevaluate past approaches, even those that were previously successful. Just because something worked before does not mean that it is still the best method. Grace Hopper, a computer scientist, mathematician, and United States Navy rear admiral, cautioned against blind adherence to tradition, saying that “we’ve always done it this way” is a dangerous mindset. We must be willing to question the old ways and explore new and potentially better methods.

The AWS Well-Architected Framework advocates for an evolutionary architecture approach to system design. Traditional architectures are often designed as static, with only a few major version updates during the system’s lifetime. However, as businesses and requirements change over time, initial architectural decisions can limit the ability to adapt and evolve the system. Cloud computing enables capabilities like automated testing and lower-risk design changes, which allows systems to evolve continually rather than being constrained by the original design. An evolutionary architecture positions businesses to take advantage of new innovations and changes as part of standard practice. Rather than being locked into original architectural choices, an evolutionary approach fosters ongoing adaptation and modernization as requirements shift. This contrasts with traditional fixed architectures that make it difficult to evolve over time and provides greater flexibility to evolve systems iteratively.

The Operational Excellence Pillar includes implementation of observability to understand system behavior, safe automation of processes, frequent but reversible changes, regular refinement of operations procedures, proactive anticipation potential failures proactively, and distribution of learnings from operational events and metrics to drive continuous improvement.

Overall, the Well-Architected Framework provides guidance on evolutionary architecture and operations processes to effectively manage increasing software complexity over time.

Conclusion

Frugality is about maximizing value, rather than just minimizing costs. Following AWS Well-Architected Framework best practices regarding security, reliability, and operational excellence can help realize frugal yet robust architectures. True frugality involves optimizing costs by aligning spending with areas that deliver the highest business value and impact. The Well-Architected Framework provides guidance for making architectural decisions that increase efficiency, lower risks, and maximize return on cloud investments. This involves determining priorities, understanding sources of value, and making informed trade-off decisions based on those priorities. It’s important to avoid indiscriminate cost-cutting and instead focus on resources on what matters most to drive value for the organization. By following Well-Architected best practices, companies can practice frugality in a strategic way that balances optimization with business goals.

Start your Frugal Architecture journey with AWS Well-Architected today by reading the documentation or visiting the AWS Well-Architected Tool in the console.

Introducing the Māori Data Lens for the Well-Architected Framework

Post Syndicated from Craig Hind original https://aws.amazon.com/blogs/architecture/introducing-the-maori-data-lens-for-the-well-architected-framework/

In Aotearoa New Zealand, we have been listening and learning to better understand Māori aspirations when using cloud technology. We have been learning from Māori customers, partners, and advisors who have helped us on this journey. A common theme was how to safeguard Māori data in a digital world. Together with a group of Māori advisers, we are excited to introduce the first iteration of a Māori Data Lens for the AWS Well-Architected Framework. This lens is the first of its kind for AWS globally that focuses on indigenous data, specifically Māori data considerations.

An AWS Well-Architected Framework lens is designed to provide a technology, industry, or domain specific perspective aligned with the AWS Well-Architected Framework. The Māori Data Lens allows customers to apply important Māori data considerations when designing and operating reliable, secure, efficient, and cost-effective systems in the cloud. This lens is designed to be a living resource that can grow and adapt alongside the evolving questions and considerations Māori have about how to secure and protect their data as a taonga (treasure). We hope this lens will be valuable in empowering individuals and organisations to design, build, and operate applications and workloads in the AWS Cloud in ways that can align with Māori values and expectations across the six pillars of the Well-Architected Framework: Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability. These are not a rigid set of rules, but instead a set of guiding principles.

This lens is designed to complement invaluable te ao Māori knowledge and expertise. It’s important to consult, build trust, and reflect Māori voices in digital and technology choices. AWS customers can consult and partner with their Māori customers to build systems in a way that responsibly interact with their Māori data. This lens is a framework of practical questions and considerations. When combined with Māori knowledge and expertise, AWS customers can begin to use cloud technology in a way that empowers adherence to important cultural and ethical dimensions for safeguarding Māori data. As a starting point, we have sought to align the insights shared with us to our AWS best practices for architecting secure, reliable, and cost-effective applications in the AWS Cloud. Together, these guidelines support the durability and protection of Māori data.

At AWS, we have always believed it is essential that our customers have control over their data. We strive to give customers choice in how to secure and manage their data in the cloud in accordance with their needs. This has been true from the very beginning, when we were the only major cloud provider to allow our customers to control the geographic location of their data, never moving customer data without explicit instruction from the customer.

The launch of an AWS Local Zone in Auckland in 2023 and the coming AWS Region in Aotearoa gives all New Zealanders the choice to store their data onshore in Aotearoa New Zealand in the AWS Cloud without compromising on performance, innovation, scale, or security. We also know that some customers have needs that go beyond where their data is stored. We’re committed to expanding our understanding and our capability to help all customers meet their particular needs and best serve their own customers, to protect their data, and to meet legal and regulatory requirements.

Advice and feedback to date has been instrumental in helping to shape this resource, and we are deeply grateful for the ongoing partnership and insights. We recognise there are different perspectives, and that tikanga (protocol/practice) and experience among Māori on this topic continues to evolve. We welcome feedback on enhancing this resource to better serve the needs of our Māori customers and partners. To provide feedback, reach out to us using the feedback feature on the lens document or your local AWS account team.

We’d like to thank AWS partner HTK Group, as well as Māori technology and data experts who advised us on this work including Renata Hakiwai, Lee Timutimu, Nikora Ngaropo, Ngapera Riley, Wade Reweti, Atawhai Tibble and Eli Pohio. In their words:

“In this rapidly evolving digital landscape, the importance of understanding, organising, and harnessing data cannot be overstated. For our Māori communities, this holds even greater significance, as data can be a taonga or a treasure that represents the collective wisdom and knowledge passed down through generations.

Nā tō rourou, nā taku rourou, ka ora ai te iwi. With your food basket and my food basket, the people will thrive.

Mauri ora!”

Read the Māori Data Lens, or contact your AWS account team for more information.

Let’s Architect! Designing Well-Architected systems

Post Syndicated from Vittorio Denti original https://aws.amazon.com/blogs/architecture/lets-architect-well-architected-systems/

The design of cloud workloads can be a complex task, where a perfect and universal solution doesn’t exist. We should balance all the different trade-offs and find an optimal solution based on our context. But how does it work in practice? Which guiding principles should we follow? Which are the most important areas we should focus on?

In this blog, we will try to answer some of these questions by sharing a set of resources related to the AWS Well-Architected Framework. The Framework shares a set of methods to help you understand the pros and cons of decisions you make while building cloud systems. By following this resource, you will learn architectural best practices for designing and operating reliable, secure, efficient, cost-effective, and sustainable systems in the cloud. The framework is constantly updated; it evolves as the technology landscape changes. Check out the latest updates from June 2024.

Build secure applications on AWS the Well-Architected way

The AWS Well-Architected Framework is constantly updated across all six pillars. The security pillar added a new best practice area: application security (AppSec). In this session, you can learn about the best practices highlighted in this area. Review four key domains: organization and culture, security of the pipeline, security in the pipeline, and dependency management. Each area provides a set of principles that you can implement and provides a complete view of how you design, develop, build, deploy, and operate secure workloads in the cloud.

Security should be part of the end-to-end development process, and implementing best practices both in the application code as well as in the underlying infrastructure components.

Figure 1. Security should be part of the end-to-end development process, and implementing best practices both in the application code as well as in the underlying infrastructure components.

Take me to this video

Announcing the AWS Well-Architected Mergers and Acquisitions Lens

How can we integrate different systems as a consequence of an acquisition? Mergers and acquisitions operations bring different people with different backgrounds together, with a need of driving systems convergence. Both organization and technical challenges can arise in this scenario. The Mergers and Acquisitions (M&A) Lens is a collection of customer-proven design principles, best practices, and prescriptive guidance to help you integrate the IT systems of two or more organizations. This lens helps companies follow AWS prescribed best practices during technical integration, drive cost optimization, and expedite merger and acquisition value realization.

If the seller company runs on another cloud platform or on-premises, the acquirer should plan a cloud migration while guaranteeing continuity of service.

Figure 2. If the seller company runs on another cloud platform or on-premises, the acquirer should plan a cloud migration while guaranteeing continuity of service.

Take me to this blog

AWS Well-Architected Labs

One of the best ways to become familiar with new concepts and methodologies consist of doing hands-on work to absorb the techniques properly. For each Let’s Architect! blog, we tend to share at least one workshop associated with the topic. The AWS Well-Architected Framework covers six different pillars, so today we share the AWS Well-Architected Labs to cover each area of the framework. Feel free to jump across the different workshops and start building!

Sustainability is one of the pillars in the framework. Asynchronous and scheduled processing are key techniques for improving the sustainability and costs of cloud architectures.

Figure 3. Sustainability is one of the pillars in the framework. Asynchronous and scheduled processing are key techniques for improving the sustainability and costs of cloud architectures.

Take me to this workshop

Gain confidence in system correctness and resilience with formal methods

Distributed systems are difficult to design. It’s even more difficult to test them and prove they are working. Formal methods enable the early discovery of design bugs that can escape the guardrails of design reviews and automated testing only to get uncovered in production. This video shows how AWS uses P, an open source, state machine–based programming language for formal modelling and analysis of distributed systems.

You can learn from AWS engineers and architects how to use P for your own applications to find bugs early in the development process and increase developer velocity. This tool is used in AWS to reason out the correctness of cloud services (for example, Amazon Simple Storage Service and Amazon DynamoDB).

An example of a distributed system for processing transactions.

Figure 4. An example of a distributed system for processing transactions.

Take me to this video

See you next time!

Thanks for reading! Hopefully, you got interesting insights into the methodologies for designing Well-Architected systems. In the next blog, we will talk about multi-region architectures. We will understand when they are actually needed, and which design principles should be applied.

To revisit any of our previous posts or explore the entire series, visit the Let’s Architect! page.

AWS Weekly Roundup: AI21 Labs’ Jamba-Instruct in Amazon Bedrock, Amazon WorkSpaces Pools, and more (July 1, 2024)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-ai21-labs-jamba-instruct-in-amazon-bedrock-amazon-workspaces-pools-and-more-july-1-2024/

AWS Summit New York is 10 days away, and I am very excited about the new announcements and more than 170 sessions. There will be A Night Out with AWS event after the summit for professionals from the media and entertainment, gaming, and sports industries who are existing Amazon Web Services (AWS) customers or have a keen interest in using AWS Cloud services for their business. You’ll have the opportunity to relax, collaborate, and build new connections with AWS leaders and industry peers.

Let’s look at the last week’s new announcements.

Last week’s launches
Here are the launches that got my attention.

AI21 Labs’ Jamba-Instruct now available in Amazon Bedrock – AI21 Labs’ Jamba-Instruct is an instruction-following large language model (LLM) for reliable commercial use, with the ability to understand context and subtext, complete tasks from natural language instructions, and ingest information from long documents or financial filings. With strong reasoning capabilities, Jamba-Instruct can break down complex problems, gather relevant information, and provide structured outputs to enable uses like Q&A on calls, summarizing documents, building chatbots, and more. For more information, visit AI21 Labs in Amazon Bedrock and the Amazon Bedrock User Guide.

Amazon WorkSpaces Pools, a new feature of Amazon WorkSpaces – You can now create a pool of non-persistent virtual desktops using Amazon WorkSpaces and save costs by sharing them across users who receive a fresh desktop each time they sign in. WorkSpaces Pools provides the flexibility to support shared environments like training labs and contact centers, and some user settings like bookmarks and files stored in a central storage repository such as Amazon Simple Storage Service (Amazon S3) or Amazon FSx can be saved for improved personalization. You can use AWS Auto Scaling to automatically scale the pool of virtual desktops based on usage metrics or schedules. For pricing information, refer to the Amazon WorkSpaces Pricing page.

API-driven, OpenLineage-compatible data lineage visualization in Amazon DataZone (preview)Amazon DataZone introduces a new data lineage feature that allows you to visualize how data moves from source to consumption across organizations. The service captures lineage events from OpenLineage-enabled systems or through API to trace data transformations. Data consumers can gain confidence in an asset’s origin, and producers can assess the impact of changes by understanding its consumption through the comprehensive lineage view. Additionally, Amazon DataZone versions lineage with each event to enable visualizing lineage at any point in time or comparing transformations across an asset or job’s history. To learn more, visit Amazon DataZone, read my News Blog post, and get started with data lineage documentation.

Knowledge Bases for Amazon Bedrock now offers observability logs – You can now monitor knowledge ingestion logs through Amazon CloudWatch, S3 buckets, or Amazon Data Firehose streams. This provides enhanced visibility into whether documents were successfully processed or encountered failures during ingestion. Having these comprehensive insights promptly ensures that you can efficiently determine when your documents are ready for use. For more details on these new capabilities, refer to the Knowledge Bases for Amazon Bedrock documentation.

Updates and expansion to the AWS Well-Architected Framework and Lens Catalog – We announced updates to the AWS Well-Architected Framework and Lens Catalog to provide expanded guidance and recommendations on architectural best practices for building secure and resilient cloud workloads. The updates reduce redundancies and enhance consistency in resources and framework structure. The Lens Catalog now includes the new Financial Services Industry Lens and updates to the Mergers and Acquisitions Lens. We also made important updates to the Change Enablement in the Cloud whitepaper. You can use the updated Well-Architected Framework and Lens Catalog to design cloud architectures optimized for your unique requirements by following current best practices.

Cross-account machine learning (ML) model sharing support in Amazon SageMaker Model RegistryAmazon SageMaker Model Registry now integrates with AWS Resource Access Manager (AWS RAM), allowing you to easily share ML models across AWS accounts. This helps data scientists, ML engineers, and governance officers access models in different accounts like development, staging, and production. You can share models in Amazon SageMaker Model Registry by specifying the model in the AWS RAM console and granting access to other accounts. This new feature is now available in all AWS Regions where SageMaker Model Registry is available except GovCloud Regions. To learn more, visit the Amazon SageMaker Developer Guide.

AWS CodeBuild supports Arm-based workloads using AWS Graviton3AWS CodeBuild now supports natively building and testing Arm workloads on AWS Graviton3 processors without additional configuration, providing up to 25% higher performance and 60% lower energy usage than previous Graviton processors. To learn more about CodeBuild’s support for Arm, visit our AWS CodeBuild User Guide.

For a full list of AWS announcements, be sure to keep an eye on the What’s New at AWS page.

We launched existing services and instance types in additional Regions:

Other AWS news
Here are some additional news items that you might find interesting:

Top reasons to build and scale generative AI applications on Amazon Bedrock – Check out Jeff Barr’s video, where he discusses why our customers are choosing Amazon Bedrock to build and scale generative artificial intelligence (generative AI) applications that deliver fast value and business growth. Amazon Bedrock is becoming a preferred platform for building and scaling generative AI due to its features, innovation, availability, and security. Leading organizations across diverse sectors use Amazon Bedrock to speed their generative AI work, like creating intelligent virtual assistants, creative design solutions, document processing systems, and a lot more.

Four ways AWS is engineering infrastructure to power generative AI – We continue to optimize our infrastructure to support generative AI at scale through innovations like delivering low-latency, large-scale networking to enable faster model training, continuously improving data center energy efficiency, prioritizing security throughout our infrastructure design, and developing custom AI chips like AWS Trainium to increase computing performance while lowering costs and energy usage. Read the new blog post about how AWS is engineering infrastructure for generative AI.

AWS re:Inforce 2024 re:Cap – It’s been 2 weeks since AWS re:Inforce 2024, our annual cloud-security learning event. Check out the summary of the event prepared by Wojtek.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Summits – Join free online and in-person events that bring the cloud computing community together to connect, collaborate, and learn about AWS. To learn more about future AWS Summit events, visit the AWS Summit page. Register in your nearest city: New York (July 10), Bogotá (July 18), and Taipei (July 23–24).

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are in Cameroon (July 13), Aotearoa (August 15), and Nigeria (August 24).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Esra

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

Announcing updates to the AWS Well-Architected Framework guidance

Post Syndicated from Haleh Najafzadeh original https://aws.amazon.com/blogs/architecture/announcing-updates-to-the-aws-well-architected-framework-guidance-2/

We are excited to announce the availability of an enhanced AWS Well-Architected Framework. In this update, you’ll find expanded guidance across all six pillars of the Framework: Operational ExcellenceSecurityReliabilityPerformance EfficiencyCost Optimization, and Sustainability.

In this release, we updated the implementation guidance for the new and existing best practices to be more prescriptive. This includes enhanced recommendations and steps on reusable architecture patterns focused on specific business outcomes.

A brief history

The Well-Architected Framework is a collection of best practices that allow customers to evaluate and improve the design, implementation, and operations of their workloads in the cloud.

2024 AWS Well-Architected guidance timeline

Figure 1. 2024 AWS Well-Architected guidance timeline

In 2012, we published the first version of the Framework. In 2015, we released the AWS Well-Architected Framework whitepaper. We added the Operational Excellence pillar in 2016. We released pillar-specific whitepapers and AWS Well-Architected Lenses in 2017. The following year, the AWS Well-Architected Tool was launched.

In 2020, we released the new version of the Well-Architected Framework guidance, more lenses, and an API integration with the AWS Well-Architected Tool. We added the sixth pillar, Sustainability, in 2021. In 2022, dedicated HTML pages were introduced for each consolidated best practice across all six pillars, with several best practices updated with improved prescriptive guidance. By December 2023, we improved more than 75% of the Framework’s best practices. As of June 2024, more than 95% of the Framework’s best practices have been refreshed at least once.

What’s new

The Well-Architected Framework supports customers as they mature in their cloud journey by providing guidance to help achieve accurate business, environment, and workload solutions. Well-Architected is committed to providing such information to customers by continually evolving and updating our guidance.

The content updates and prescriptive guidance improvements in this release provide more complete coverage across AWS, helping customers make informed decisions when developing implementation plans. We added or expanded on guidance for the following services in this update: Amazon Chime, Amazon CloudWatch, Amazon CodeGuru Security, Amazon CodeWhisperer, Amazon Devops Guru, Amazon Elastic Container Service (Amazon ECS), Amazon Elastic Kubernetes Service (Amazon EKS), Amazon ElastiCache, Amazon EventBridge, Amazon GuardDuty, Amazon Q, Amazon Route 53, Amazon Security Lake, Amazon Simple Notification Service (Amazon SNS), AWS Billing and Cost Management, AWS Budgets, AWS Compute Optimizer, AWS Config, AWS Control Tower, AWS Cost Optimization Hub, AWS Customer Carbon Footprint Tool, AWS Data Exports, AWS Data Lifecycle Manager, AWS Elastic Disaster Recovery, AWS Fault Injection Service, AWS Global Accelerator, AWS Health, AWS Local Zones, AWS Organizations, AWS Outposts, AWS Resilience Hub, AWS Security Hub, AWS Systems Manager, AWS Trusted Advisor, and AWS Wickr.

Pillar updates

Operational Excellence

In the Operational Excellence Pillar, we updated 30 best practices across six questions. This includes OPS01, OPS02, OPS03, OPS07, OPS10, and OPS11. This update includes a refreshed structure and improved prescriptive guidance with updates on observability, generative AI capabilities, operating models, and the evolution of operational practices.

As part of this update, we consolidated four best practices into two (OPS01-BP07 merged into OPS01-BP06, OPS03-BP08 merged into OPS03-BP04) and changed the titles of seven best practices. Additionally, we added one new design principal to highlight the importance of aligning operating models to business outcomes and reordered design principles according to their priority from foundational to specialized. We updated three design principles and changed the title of one design principle. We’ve also updated the operating model guidance section of the pillar to be more prescriptive, showcasing pathways to evolving operating models.

The implementation guidance in best practices includes guidance on implementing generative AI capabilities with Amazon Q (Q Developer, Q Business, Q in QuickSight), the latest capabilities from Amazon CloudWatch Network Monitor, Amazon CloudWatch Internet Monitor, Amazon CloudWatch Logs, Amazon CloudWatch best practice alarms, cross-account observability, log-based alarms, log data protection, and AWS Health.

Security

In the Security Pillar, we updated 28 best practices across 10 questions. This includes SEC01, SEC02, SEC03, SEC04, SEC05, SEC06, SEC07, SEC08, SEC09, and SEC10. Best practice updates include removing duplication, clarifying desired outcomes, and providing robust prescriptive implementation guidance. As part of this update, we merged SEC01-BP05 into SEC01-BP04. We deleted two practices, SEC08-BP05 and SEC09-BP03, to remove the duplication of guidance covered across other existing practices. We updated the titles for 14 practices and changed the order of nine practices to improve clarity and flow.

Reliability

In the Reliability Pillar, we updated 11 best practices across six questions. This includes REL02, REL04, REL05, REL06, REL07, and REL08, with three best practices changing titles including REL04-BP01, REL05-BP06, and REL06-BP05. We improved resources available in best practices to include more recent blog posts, technical talks, and presentations. We also improved the prescriptive guidance by expanding on implementation steps. New services and service features added to the best practices guidance for AWS Resilience Hub, Amazon Route 53, Amazon Route53 Application Recovery Controller, AWS Fault Injection Service, and Amazon CloudWatch Synthetics.

Performance Efficiency

In the Performance Efficiency Pillar, we updated nine best practices across three questions. This includes PERF01, PERF03, and PERF05. We improved the prescriptive guidance on these best practices and added pillar-specific guidance on services including Amazon Devops Guru and Amazon ElastiCache Serverless. We’ve updated the resources section of all best practices with new and relevant resources.

Cost Optimization

In the Cost Optimization Pillar, we updated eight best practices across five questions. This includes COST01, COST02, COST03, COST05, and COST11. One new best practice added in COST06 highlights the benefits of using shared resources for organizational cost optimization. The improved best practices include guidance on AWS services and features including the AWS Cost Optimization Hub, AWS Billing and Cost Management features, and AWS Data Exports. These updates also cover sample key performance indicators (KPIs) for tracking optimization efforts, elaborate on the use of cost allocation tags, and discuss the split cost allocation for Amazon EKS and Amazon ECS to separate costs of containerized workloads. Additionally, the updates offer improved prescriptive and clear guidance on budgeting and forecasting. Finally, you’ll find guidance on using automations to reduce costs.

Sustainability

In the Sustainability Pillar, we updated 18 best practices across five questions. This includes SUS01, SUS02, SUS03, SUS04, SUS05, and SUS06. We improved the prescriptive guidance on these best practices, and added Pillar-specific guidance on services, including AWS Local Zones, AWS Outposts, Amazon Chime, AWS Wickr, Amazon CodeWhisperer, and AWS Customer Carbon Footprint Tool. We’ve expanded lists of resources across all best practices with new and relevant resources.

Conclusion

This release includes updates and improvements to the Framework guidance totaling 105 best practices. As of this release, we’ve updated 95% of the existing Framework best practices at least once since October 2022. With this release, we have refreshed 100% of the Operational Excellence, Security, Performance Efficiency, Cost Optimization, and Sustainability Pillars, as well as 79% of Reliability Pillar best practices. Best practice updates in this release across Operational Excellence, Security, and Reliability (a total of 66) are first-time updates since major Framework improvements started in 2022.

The content is available in 11 languages: English, Spanish, French, German, Italian, Japanese, Korean, Indonesian, Brazilian Portuguese, Simplified Chinese, and Traditional Chinese.

Updates in this release are also available in the AWS Well-Architected Tool, which you can use to review your workloads, address important design considerations, and help you follow the AWS Well-Architected Framework guidance.

Ready to get started? Review the updated AWS Well-Architected Framework Pillar best practices and pillar-specific whitepapers.

Have questions about some of the new best practices or most recent updates? Join our growing community on AWS re:Post.

Top Architecture Blog Posts of 2023

Post Syndicated from Andrea Courtright original https://aws.amazon.com/blogs/architecture/top-architecture-blog-posts-of-2023/

2023 was a rollercoaster year in tech, and we at the AWS Architecture Blog feel so fortunate to have shared in the excitement. As we move into 2024 and all of the new technologies we could see, we want to take a moment to highlight the brightest stars from 2023.

As always, thanks to our readers and to the many talented and hardworking Solutions Architects and other contributors to our blog.

I give you our 2023 cream of the crop!

#10: Build a serverless retail solution for endless aisle on AWS

In this post, Sandeep and Shashank help retailers and their customers alike in this guided approach to finding inventory that doesn’t live on shelves.

Building endless aisle architecture for order processing

Figure 1. Building endless aisle architecture for order processing

Check it out!

#9: Optimizing data with automated intelligent document processing solutions

Who else dreads wading through large amounts of data in multiple formats? Just me? I didn’t think so. Using Amazon AI/ML and content-reading services, Deependra, Anirudha, Bhajandeep, and Senaka have created a solution that is scalable and cost-effective to help you extract the data you need and store it in a format that works for you.

AI-based intelligent document processing engine

Figure 2: AI-based intelligent document processing engine

Check it out!

#8: Disaster Recovery Solutions with AWS managed services, Part 3: Multi-Site Active/Passive

Disaster recovery posts are always popular, and this post by Brent and Dhruv is no exception. Their creative approach in part 3 of this series is most helpful for customers who have business-critical workloads with higher availability requirements.

Warm standby with managed services

Figure 3. Warm standby with managed services

Check it out!

#7: Simulating Kubernetes-workload AZ failures with AWS Fault Injection Simulator

Continuing with the theme of “when bad things happen,” we have Siva, Elamaran, and Re’s post about preparing for workload failures. If resiliency is a concern (and it really should be), the secret is test, test, TEST.

Architecture flow for Microservices to simulate a realistic failure scenario

Figure 4. Architecture flow for Microservices to simulate a realistic failure scenario

Check it out!

#6: Let’s Architect! Designing event-driven architectures

Luca, Laura, Vittorio, and Zamira weren’t content with their four top-10 spots last year – they’re back with some things you definitely need to know about event-driven architectures.

Let's Architect

Figure 5. Let’s Architect artwork

Check it out!

#5: Use a reusable ETL framework in your AWS lake house architecture

As your lake house increases in size and complexity, you could find yourself facing maintenance challenges, and Ashutosh and Prantik have a solution: frameworks! The reusable ETL template with AWS Glue templates might just save you a headache or three.

Reusable ETL framework architecture

Figure 6. Reusable ETL framework architecture

Check it out!

#4: Invoking asynchronous external APIs with AWS Step Functions

It’s possible that AWS’ menagerie of services doesn’t have everything you need to run your organization. (Possible, but not likely; we have a lot of amazing services.) If you are using third-party APIs, then Jorge, Hossam, and Shirisha’s architecture can help you maintain a secure, reliable, and cost-effective relationship among all involved.

Invoking Asynchronous External APIs architecture

Figure 7. Invoking Asynchronous External APIs architecture

Check it out!

#3: Announcing updates to the AWS Well-Architected Framework

The Well-Architected Framework continues to help AWS customers evaluate their architectures against its six pillars. They are constantly striving for improvement, and Haleh’s diligence in keeping us up to date has not gone unnoticed. Thank you, Haleh!

Well-Architected logo

Figure 8. Well-Architected logo

Check it out!

#2: Let’s Architect! Designing architectures for multi-tenancy

The practically award-winning Let’s Architect! series strikes again! This time, Luca, Laura, Vittorio, and Zamira were joined by Federica to discuss multi-tenancy and why that concept is so crucial for SaaS providers.

Let's Architect

Figure 9. Let’s Architect

Check it out!

And finally…

#1: Understand resiliency patterns and trade-offs to architect efficiently in the cloud

Haresh, Lewis, and Bonnie revamped this 2022 post into a masterpiece that completely stole our readers’ hearts and is among the top posts we’ve ever made!

Resilience patterns and trade-offs

Figure 10. Resilience patterns and trade-offs

Check it out!

Bonus! Three older special mentions

These three posts were published before 2023, but we think they deserve another round of applause because you, our readers, keep coming back to them.

Thanks again to everyone for their contributions during a wild year. We hope you’re looking forward to the rest of 2024 as much as we are!

Announcing the AWS Well-Architected Framework DevOps Guidance

Post Syndicated from Michael Rhyndress original https://aws.amazon.com/blogs/devops/announcing-the-aws-well-architected-framework-devops-guidance/

Today, Amazon Web Services (AWS) announced the launch of the AWS Well-Architected Framework DevOps Guidance. The AWS DevOps Guidance introduces the AWS DevOps Sagas—a collection of modern capabilities that together form a comprehensive approach to designing, developing, securing, and efficiently operating software at cloud scale. Taking the learnings from Amazon’s own transformation journey and our experience managing global cloud services, the AWS DevOps Guidance was built to equip organizations of all sizes with best practice culture, processes, and technical capabilities that help to deliver business value and applications more securely and at a higher velocity.

A Glimpse into Amazon’s DevOps Transformation

In the early 2000s, Amazon went through its own DevOps transformation which led to an online bookstore forming the AWS cloud computing division. Today, AWS provides a wide range of products and services for global customers that are powered by that same innovative DevOps approach. Due to the positive effects of this transformation, AWS recognizes the significance of DevOps and has been at the forefront of its adoption and implementation.

Amazon’s own journey, along with the collective experience gained from assisting customers as they modernize and migrate to the cloud, provided insight into the capabilities which we believe make DevOps adoption successful. With these learnings, we created the DevOps Sagas to help our customers sustainably adopt and practice DevOps through the implementation of an interconnected set of capabilities. Each DevOps Saga includes prescriptive guidance for capabilities that provide indicators of success, metrics to measure, and common anti-patterns to avoid.

Introducing The DevOps Sagas

The DevOps Sagas are core domains within the software delivery process that collectively form AWS DevOps best practices. Together, they encompass a collection of modern capabilities representing a comprehensive approach to designing, developing, securing, and efficiently operating software at cloud scale. You can use the DevOps Sagas as a common definition of what DevOps means to your organization by aligning on a shared understanding within your organization and to consistently measure DevOps adoption over time. The 5 DevOps Sagas are:

  • Organizational Adoption Saga: Inspires the formation of a customer-centric, adaptive culture focused on optimizing people-driven processes, personal and professional development, and improving developer experience to set the foundation for successful DevOps adoption.
  • Development Lifecycle Saga: Aims to enhance the organization’s capacity to develop, review, and deploy workloads swiftly and securely. It leverages feedback loops, consistent deployment methods, and an ‘everything-as-code’ approach to attain efficiency in deployment.
  • Quality Assurance Saga: Advocates for a proactive, test-first methodology integrated into the development process to ensure that applications are well-architected by design, secure, cost-efficient, sustainable, and delivered with increased agility through automation.
  • Automated Governance Saga: Facilitates directive, detective, preventive, and responsive measures at all stages of the development process. It emphasizes risk management, business process adherence, and application and infrastructure compliance at scale through automated processes, policies, and guardrails.
  • Observability Saga: Presents an approach to incorporating observability within environment and workloads, allowing teams to detect and address issues, improve performance, reduce costs, and ensure alignment with business objectives and customer needs.

DevOps Sagas display image defining the definition of Sagas, Capabilities, Indicators, Metrics, and Anti-Patterns. AWS DevOps Sagas provides foundational DevOps capabilities, indicators, and metrics aligned to AWS best practices. Sagas are core domains that collectively form AWS DevOps best practices. Capabilities are individual practices with differentiated outcomes that form a Saga. Indicators objectively measure qualities of each capability. Metrics quantify and measure proficiency of each capability. Anti-patterns avoid behaviors that may seem beneficial but lead to inefficient outcomes.

Who should use the AWS DevOps Guidance?

We recognize that every organization is unique and that there is no one-size-fits-all approach to practicing DevOps. The recommendations and examples provided can be tailored to suit your organization’s environment, quality, and security needs. The AWS DevOps Guidance is designed for a wide range of professionals and organizations, including startups exploring DevOps for the first time, established enterprises refining their processes, public sector companies, cloud-native businesses, and customers migrating to the AWS Cloud. Whether you are steering strategic direction as a Chief Technology Officer (CTO) or Chief Information Security Officer (CISO), a developer or architect actively engaged in designing and deploying workloads, or in a compliance role overseeing quality assurance, auditing, or governance, this guidance is tailored to help you.

Next Steps

With the release of the AWS DevOps Guidance, we encourage you, our customers, to download and read the document, as well as implement and test your workloads in accordance with the recommendations within. Use the AWS DevOps Guidance in tandem with the AWS Well-Architected Framework to conduct an assessment of your organization and individual workload’s adherence to DevOps best practices to pinpoint areas of strength and opportunities for improvement. Collaborate with your teams – from developers to operations and decision-makers – to share insights from your assessment. Use the insights gained from the AWS DevOps Guidance to prioritize areas of improvement and iteratively improve your DevOps capabilities.

Find the AWS DevOps Guidance on the AWS Well-Architected website or contact your AWS account team for more information. As with the AWS Well-Architected Framework and other industry and technology guidance, we recommend leveraging the AWS DevOps Guidance early and often – as you approach architectural and service design decisions, and whenever you carry out Well-Architected reviews. As you use the AWS DevOps Guidance, we would appreciate your comments and feedback to help us improve as best practices and technology evolve. We will continually refresh the content as we identify new best practices, metrics, and common scenarios.