На второ четене: „За какво мисли човек“

Post Syndicated from Стефан Иванов original https://www.toest.bg/na-vtoro-chetiene-za-kakvo-misli-chovek/

„За какво мисли човек“ от Васил Габор

На второ четене: „За какво мисли човек“

превод от украински Павлина Мартинова, изд. „Ерго“, 2023

Първото нещо, за което ме подсети заглавието на този сборник с разкази, е „За какво мислите“ – подканата на Facebook, когато още не си започнал да пишеш публикация. Украинският писател Васил Габор обаче е възможно най-далеч от света на социалните мрежи, от суетнята, суматохата и поредните скандали на деня. Писането му е лаконично и прозрачно, лишено от големи думи и обобщения, взряно в детайли, дреболии и чудеса. Писането му напомня на Радичковото, защото не се наблюдава умора от чудото, напротив, удоволствието от очарованието на света е невинно и сърцато.

Габор казва:

… всеки писател си има своя карма: едни пишат много, други – малко. Аз пиша много малко. Първата си оригинална „Книга на екзотичните сънища и реалните събития“ писах двайсет години и изписах в нея всички думи, които знаех, а ето към тази, втората, вървях почти петнайсет години, събирайки за нея нови думи, образи и впечатления. Но не бързах да пиша. Защото не ми се искаше да прилича на първата, а и впоследствие ми стана безинтересно да пиша разкази или новели, като спазвам строго изискванията на жанра и измислям нови герои.

Нямам усещането, че тази проява на скромност, за разлика от толкова много други, прикрива раздуто его и безмерни амбиции. Постепенно Габор стига до решението книгата му да бъде в японския жанр „дзуйхицу“, който се характеризира със свободно и асоциативно, фрагментарно и есеистично писане. Родоначалничката на жанра е легендарната и добре позната в България придворна дама Сей Шонагон със своите неподражаеми и красиви „Записки под възглавката“, създадени преди хилядолетие. Парадоксално, писането на Шонагон е изключително съвременно и днес заради списъците си, кратките истории и анекдоти, описанието на всекидневни случки и пейзажи. Някои от тях са точно като разговори с близък от днес или вчера, в чат или на живо.

Габор по спокоен, заземяващ и медитативен начин разкрива личния си и непосредствен свят. Той изрежда за какво мисли човек, докато отива на работа – за улицата, за тъжните неща, за света на детството, за това кое носи удоволствие и радва. Но мисли и за неща, за които не му се иска. Натрапчивите мисли могат да пробият всяка защита. Друг автор, с който спонтанно откривам близост, е Кенет Уайт, също заслужено популярен в България. Неговата особена смесица между източна уединена естетика и западна ирония и отказ от конформизъм също са в родословното дърво на поетиката на Габор.

На пръв поглед изглежда лесно или ненужно фокусът върху очевидното да е толкова интензивен акт, но в това няма нищо самоцелно. Популярни и болезнено актуални са думите на Оруел, че

вече сме потънали до дълбочина, в която потвърждаването на очевидното е първото задължение на интелигентните хора. Ако свободата изобщо означава нещо, то е правото да казваш на хората това, което не искат да чуят. Във времена на всеобща измама да казваш истината ще бъде революционен акт.

Когато Габор пише тази книга, в Лвов и в Украйна все още няма война, но тя от години е на прага. Неговият писателски и човешки опит е да реабилитира очевидното и простото, да създава противоотрова по един безхитростен и честен начин, да свидетелства за това, което е и каквото е, а не за това какво може да бъде. Далечни са му абстракцията и плакатната идеология. В писането на украинския автор има воля да види и разбере тайните неща, трагедията на птичетата, които са паднали от гнездото, да чуе човека в ъгъла, да види сградата на живота му, да види ангела в спящото дете. И не, това не са сантиментални и трогателни по кичозен начин разкази.

Споменах, че се родее с Радичков и с неговия поглед, взрян в неопетненото чудо. Габор също е от страната на светлата и добронамерена наивност. В нея има призраци и върколаци, магия и блаженство, съдба и случайност.

Това е проза, която е старовремска, класическа и ретро по възможно най-добрия начин. В нея го има палавия смях на джаза, но го има и оправдания плач и скръб по един свят, който вече е друг.

Във време на виртуална реалност да пишеш за това, което наистина живееш и виждаш, е важно. Важно е, защото светът не се превръща и няма да се превърне в метареалност, която има някакво отношение към интелектуални, културни или материални натрупвания. Светът няма да се побере в телефон или приложение. Не може да бъде опростен до черно и бяло. И това трябва да се припомня, защото самото нещо постепенно е измествано от символа, територията е замествана от картата и това отдалечаване от естеството на всекидневието започва още от детството.

Книгата на Габор е като гръмоотвод, който отвежда електричеството на тревогата и стреса под земята, обезопасява ги, за да не се превърнат фантазмите в реални болки и причини за крах.

Крахът е обратим. Сборникът няма такъв залог и амбиция, но създава пространство на силни емоции и екзистенциални размисли. Те резонират с масово вроденото днес безпокойство, но прочитът на тази книга е трансформиращо преживяване. Освежава и вълнува.

На второ четене: „За какво мисли човек“

Няма да се въздържа да споделя част от биографията и възгледите на Габор, защото във времена на носталгици и популисти трябва да се припомнят и очевидни неща. Той е писател, литературовед и издател. Роден в Закарпатието през 1959 г. Завършва Факултета по журналистика в Лвовския университет през 1986 г. и работи в редакционните екипи на местни вестници и списания. От 1993 г. е в академичната библиотека в града. Там се съсредоточава върху изучаването на украинската периодика от XIX и XX век.

Преживял е както епохата на тоталитарния режим, така и последвалото възкръсване на независима Украйна. Животът му е пример за безграничните възможности, които предоставя свободата.

В независима Украйна аз, просто момче от планинско село, постигнах това, което някога изглеждаше невъзможно. Получих докторска степен и публикувах няколко научни книги, романи, есета, разкази. Освен това в продължение на две десетилетия ръководех издателската си инициатива „Частна колекция“. В рамките на този проект на бял свят се появиха над 200 книги и антологии на съвременни украински автори.

Габор е допринесъл и за възраждането на интереса към творчеството на забравени и забранени писатели и учени.

По времето на тоталитаризма подобни начинания биха били немислими. Ето защо за мен свободата е най-ценното понятие както в Украйна, така и в световен мащаб. За новите поколения, родени в независима Украйна, свободата е толкова естествена, колкото и въздухът, който дишат, и това е правилно. И все пак днес сме изправени пред сериозна заплаха от страна на Путинова Русия. Тя има за цел да ни лиши от най-ценните ни активи – нашата земя и нашата свобода. Твърдо вярвам, че творческото изразяване на всеки украински писател сега служи като оръжие в тази борба.

Сърцето на книгата, поне за мен, е в разказа за помориеца Стефан Кърнов и за черния пясък на плажа. От него раните зараствали, но не всички. Това обаче не отменя болезнено красивата нужда да се говори за тях.


Активните дарители на „Тоест“ получават постоянна отстъпка в размер на 20% от коричната цена на всички заглавия от каталога на издателство „Ерго“, както и на няколко други български издателства в рамките на партньорската програма Читателски клуб „Тоест“. За повече информация прочетете на toest.bg/club.

Никой от нас не чете единствено най-новите книги. Тогава защо само за тях се пише? „На второ четене“ е рубрика, в която отваряме списъците с книги, публикувани преди поне година, четем ги и препоръчваме любимите си от тях. Рубриката е част от партньорската програма Читателски клуб „Тоест“. Изборът на заглавия обаче е единствено на авторите – Стефан Иванов и Антония Апостолова, които биха ви препоръчали тези книги и ако имаше как веднъж на две седмици да се разходите с тях в книжарницата.
A vote of thanks to our Trustees

Post Syndicated from John Lazar original https://www.raspberrypi.org/blog/a-vote-of-thanks-to-our-trustees/

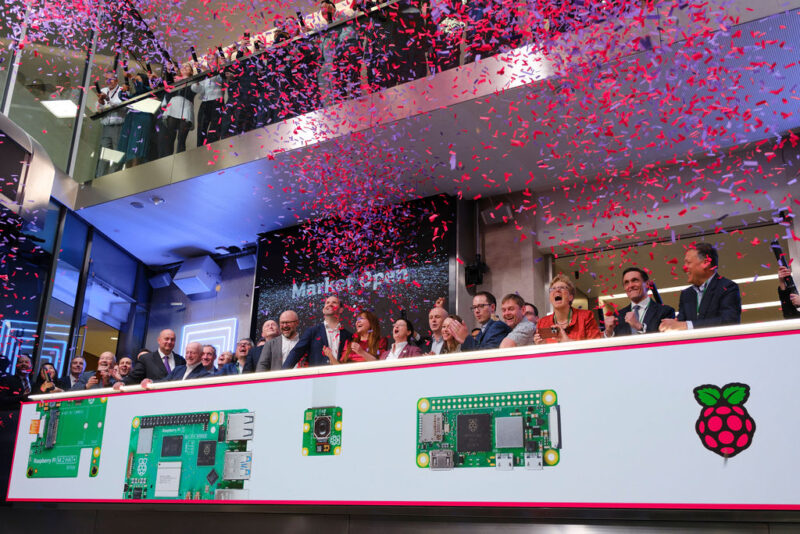
Tuesday 11 June 2024 will be remembered as one of the most important days in the history of Raspberry Pi.

Confetti rains at the introduction of Raspberry Pi Holdings PLC to the London Stock Exchange.
At the London Stock Exchange on 11 June 2024.

The successful introduction of the Raspberry Pi Foundation’s commercial subsidiary on the London Stock Exchange is a genuinely remarkable achievement. I want to put on record my huge congratulations and thanks to Eben Upton, Martin Hellawell, and the whole team at Raspberry Pi Holdings plc for everything they have done to make this possible. 

The purpose of the IPO was to secure the next stage of growth and impact for both the Foundation and the company. We have huge ambitions and the IPO has provided both organisations with the capital we need to pursue those ambitions at pace and scale. Our Chief Executive Philip Colligan has already explained what it means for the Raspberry Pi Foundation and our mission to empower young people all over the world. 

In this post, I wanted to take a moment to acknowledge the significant contribution that others have made over the years, particularly all of the Trustees who have been so generous with their time, energy, and expertise. 

Founding Trustees

The Raspberry Pi Foundation was established in 2008 by six founding Trustees: Alan Mycroft, David Braben, Eben Upton, Jack Lang, Pete Lomas, and Rob Mullins. All of them deserve credit and thanks for setting us off on this incredible journey. 

Alan, Eben, Jack, and Rob were all involved with the Computer Lab at the University of Cambridge. They were dealing with a decline in applications to study the computer science undergraduate course, which was a symptom of the much wider challenge that far too many young people weren’t getting access to opportunities to learn computer science, or getting hands-on with programming and electronics. 

David Braben brought an industry perspective, drawing on the challenges he was experiencing with recruiting engineers and programmers at the world-leading games company that he had founded, Frontier Developments.

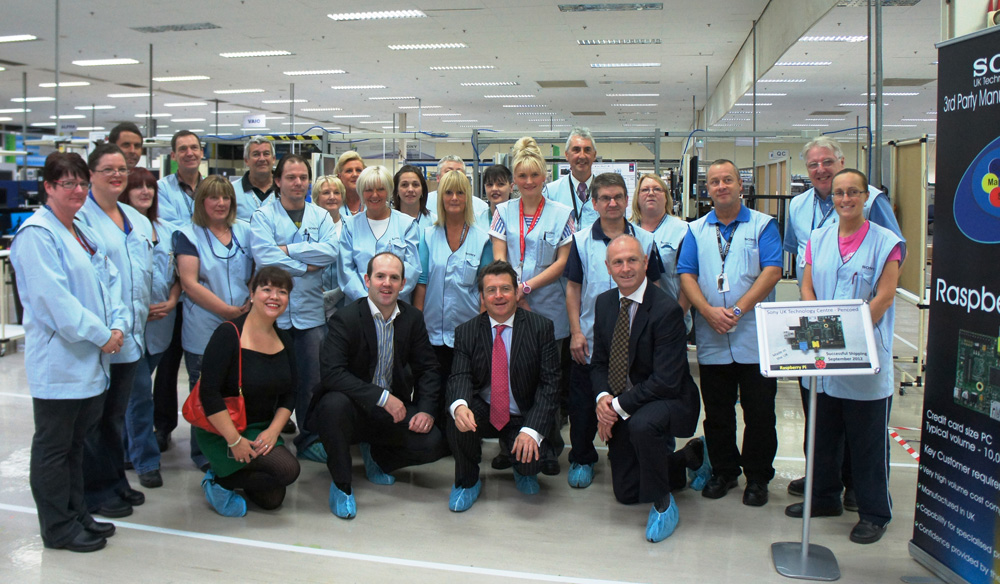
Back in 2012 at the Sony factory that produces Raspberry Pi computers in Pencoed, Wales.

For Pete Lomas, he was paying forward the support and inspiration that he received from a college technician who gave him the opportunity and encouragement to experiment with programming a DEC PDP-8. That experience ultimately led Pete to establish Norcott Technologies, an electronics design and manufacturing business that he still runs today.

The founding Trustees’ original idea was to create a low-cost programmable computer — available for the price of a textbook — that would remove price as a barrier to owning a computer and inspire young people to take their first steps with computing. It took four years for the first Raspberry Pi computer to be launched, an achievement for which Eben and Pete were rightly honoured, along with other members of the team, as recipients of the prestigious MacRobert Prize for engineering.

Combining social impact and commercial success 

What none of our founding Trustees could have predicted was the enormous commercial success of Raspberry Pi computers. In realising their vision of a low-cost programmable computer for education, the team created a new category of single-board computers that found a home with enthusiasts and industry, enabling the team to evolve — through hard work and creativity — into a business that is now entering a new phase as a listed company.

They also delivered on the original mission, with computer science at the University of Cambridge now being one of the most oversubscribed undergraduate courses in the country and many applicants citing Raspberry Pi computers as part of their introduction to programming. 

The commercial success of Raspberry Pi has enabled the Foundation to expand its educational programmes to the point where it is now established as one of the world’s leading nonprofits focused on democratising access to computing education, and is benefiting the lives of tens of millions of young people already. 

It takes a village 

While no-one really knows the origin of the proverb ‘It takes a village to raise a child’, we can all recognise the truth in that simple statement. It applies just as much for endeavours like Raspberry Pi.

Over the years, Raspberry Pi has been a genuine team game. Employees in the Foundation and our commercial subsidiary, advisers, partner organisations and supporters, volunteers and community members have all played a crucial role in the success of both the company and the Foundation.

Pete Lomas and Philip Colligan laugh on stage.
At a Raspberry Pi birthday celebration circa 2017.

Over the years there have been 21 Trustees of the Foundation, bringing an incredible range of skills and experience that has elevated our ambitions and supported the teams in both the Foundation and the company. 

All of our Trustees have provided their time and expertise for free, never receiving any financial benefit for their contribution as Trustees. 

Serving as a Trustee of a charity is a serious business, with significant responsibility and accountability. While many charities have commercial operations, there is no doubt that the scale and complexity of Raspberry Pi’s commercial business has placed significant additional responsibilities on all of our Trustees. 

I especially want to pay tribute to my predecessors as chair of the Board of Trustees: Jack Lang, one of our founding Trustees, who sadly passed away this year; and David Cleevely, who continues to support our work as a Member of the Foundation. Both Jack and David played a particularly important part in the success of Raspberry Pi. 

Welcoming our new Trustees

As we enter this new phase for the Foundation’s relationship with Raspberry Pi Holdings Ltd, we are delighted to welcome three new Trustees to the Board:

  • Andrew Sliwinski is a VP at Lego Education, formerly co-director of Scratch @ MIT, ex-Mozilla, and founder of DIY.org. Andrew is a technologist and maker with a deep understanding of education systems globally.
  • Laura Turkington leads global partnerships and programmes at EY, and was previously at Vodafone Foundation. Laura has extensive global experience (including Ireland and India), including supporting large-scale initiatives on digital skills, computing education, and AI literacy.
  • Stephen Greene is the founder and CEO of Rockcorps and the former chair of the National Citizen Service. Stephen brings huge experience of building global volunteer movements, social enterprise, marketing (especially to young people), government relations, and education of disadvantaged youth.

The post A vote of thanks to our Trustees appeared first on Raspberry Pi Foundation.

Modernize your Java application with Amazon Q Developer

Post Syndicated from Chetan Makvana original https://aws.amazon.com/blogs/devops/modernize-your-java-application-with-amazon-q-developer/

Many organizations have critical legacy Java applications that are increasingly difficult to maintain. Modernizing these applications is a necessary, daunting, and risky task that takes the focus off of creating new value or features. This includes undocumented code, outdated frameworks and libraries, security vulnerabilities, a lack of logging and error handling, and a lack of input validation. Amazon Q Developer simplifies and accelerates the modernization of existing Java applications. It can analyze code to highlight areas for potential improvements, assist with resolving technical debt, suggest code optimizations, and facilitate the transition to current frameworks and libraries.

This blog post explores how to modernize legacy Java applications using Amazon Q Developer. We will take an example of Unicorn Store API, a Java application with Java 8 running on Amazon Elastic Compute Cloud (Amazon EC2). First, we will upgrade the underlying runtime from Java 8 to Java 17 and other common dependencies, including Spring. Then, we will reduce technical debt within the code by improving modularity and logging. Finally, we will redeploy this application in a container image using a modern computing option, AWS Fargate.

The Unicorn Store API provides CRUD operations to manage Unicorn records in a database. It is built with Maven.

You will follow the below steps to modernize this application and bring it to Fargate using Amazon Q Developer.

  1. Upgrade the application to Java 17 to leverage the latest features.
  2. Reduce existing technical debt in the codebase.
  3. Make the application cloud native and deploy it to AWS.

In this walkthrough, we are using IntelliJ IDEA IDE with the latest version of Amazon Q Developer plugin for IntelliJ IDEA

Upgrade from Java 8 to Java 17

Outdated applications require increased effort to maintain security and stability. As a developer, you must continually relearn framework changes and optimizations that others have discovered in previous upgrades. The effort required to maintain the application makes it difficult to balance necessary updates with adding new features.

With Amazon Q Developer agent for code transformation, you can keep applications updated and supported in just a few steps. This removes vulnerabilities from unsupported versions, improves performance, and frees up time to focus on adding new features. Amazon Q Developer agent for code transformation accelerates application maintenance, upgrades, and migration in minutes. It enables developers to remove much of the undifferentiated work out of the tedious task of maintaining, upgrading and migrating existing application workloads, saving up to days’ or months’ worth of the undifferentiated work involved in moving from older language versions.

Let’s upgrade our Unicorn Store API from Java 8 to Java 17 using Amazon Q Developer agent for code transformation to leverage the latest features and optimization. In IntelliJ IDE, you enter /transform in the Amazon Q chat panel and provide the necessary details for Amazon Q Developer to start upgrading the project.

IntelliJ IDE showing the Amazon Q chat panel open with the /transform command entered and details provided about the project to upgrade. This triggers the Amazon Q Developer agent for code transformation to analyze the code, generate a transformation plan, and upgrade frameworks and libraries like Spring, Spring Boot, JUnit, and Log4j to be compatible with Java 17.

Amazon Q Developer agent for code transformation automatically analyzes the existing code, generates a transformation plan, and completes the transformation tasks suggested by the plan. While doing so, it upgrades popular libraries and frameworks to a version compatible with Java 17, including Spring, Spring Boot, JUnit, JakartaEE, Mockito, Hibernate, and Log4j to their latest available major versions. It also updates deprecated code components according to Java 17 recommendations. To start with the Amazon Q Developer agent for code transformation capability, you can read and follow the steps at Upgrade language versions with Amazon Q Developer agent for Code Transformation.

Once complete, you can review the transformed code, complete with build and test results, before accepting the changes.

In the IntelliJ IDE, Amazon Q Developer agent for code transformation summarizes all the changes it made after the transformation of the current project to Java 17 is complete. User clicks on the View diff button. The list of all the files that have been modified or added is displayed. User has the option to review the diff, and then accept or reject them.

Reduce technical debt in the codebase

Technical debt accumulates in any codebase over time. Some technical debt may be unavoidable to meet deadlines, but must be tracked and prioritized to pay back later. If left unmanaged, compounding technical debt will make development slower and expensive. Reducing technical debt should be an ongoing team effort, but often falls behind other priorities. Amazon Q Developer streamlines modernizing legacy Java code by identifying and remediating technical debt. Amazon Q Developer reduces the time and resources it takes to analyze the code by providing a list of issues that contribute to technical debt in a codebase. This makes it easy for software development teams to prioritize technical debt items and make informed decisions about which technical debt to address first.

Let’s find the list of technical debt in our Unicorn Store API. In IntelliJ IDE, use Send to Prompt option to send the highlighted code to the Amazon Q chat panel and prompt to provide a list of all technical debt. Amazon Q Developer lists all technical debt in detail.

In the IntelliJ IDE, user has opened the code for one of the classes (UnicornController.java in this case). User right-clicks inside this file. This opens a context window. User selects Amazon Q, then selects Send to Prompt. The code is now displayed in the Amazon Q Chat panel. The user enters this message in the chat window: “Analyze the selected code and list all technical debt”. Amazon Q Developer generates a list of all potential technical debt or areas of improvement. It explains the impact of each technical debt.

Once you identify the technical debt, the next step is to gradually remediate them. Amazon Q Developer reduces the time it takes to implement the code to remediate the technical debt. As a developer, you can interact with Amazon Q Developer agent for software development within your IDE to get help with code suggestions for a specific task that you are trying to accomplish. It uses the code in whole project as context and provides an implementation plan that includes code updates it plans to make across all the files in the project. You can review the plan, and once you are satisfied with the plan, you can ask Amazon Q Developer to generate the code based on the proposed plan. This saves developers’ effort compared to manual updates.

For the technical debt identified for Unicorn Store API in the above step, let’s use Amazon Q Developer to address the missing logging technical debt. In IntelliJ IDE, enter /dev in the Amazon Q chat panel with the details on the logging technical debt. Amazon Q Developer generates an implementation plan and code to add logging based on the full project context. To get started with Amazon Q Developer agent for software development, you can refer to the steps at Develop software with the Amazon Q Developer agent for software development.

In the IntelliJ IDE, the user opens Amazon Q Chat panel, enters /dev and provides input about the task detail “Implement logging for critical REST endpoints. Log relevant error details such as request parameters and stack traces to facilitate debugging and troubleshooting”. The Amazon Q Developer agent for software development generates the steps to implement this task, including changes that will be made to existing files and any new files that will be created. User reviews all the changes, then clicks on Generate code button. Amazon Q generates a list of code suggestions. User clicks on a file from the list, and reviews the diff between the existing code in that file, and the new code generated by Amazon Q Developer. User then clicks on Insert Code button.

Modernizing legacy Java code requires continuous refactoring to incrementally enhance quality and avoid accumulating technical debt over time. Amazon Q Developer simplifies this iterative process through its Refactor capability. Amazon Q Developer provides a refactored version of the selected code, alongside explanations of each change and its coding benefit. It helps you to understand the changes by explaining each change and the benefit of making the change in the existing code. You can read further about this capability at Explain and update code with Amazon Q Developer.

Let’s leverage this feature to refine methods in the UnicornController class in our Unicorn Store API project. Amazon Q Developer furnishes the updated code with better code readability or efficiency, among other improvements, for you to review.

In the IntelliJ IDE, user highlights a section of code (createUnicorn and updateUnicorn methods in the UnicornController class in this case), and right-clicks on the highlighted code. This opens a context window. User selects Amazon Q, and then selects Refactor code. The code is now displayed in the Amazon Q Chat panel. Amazon Q Developer generates a refactored version of the selected code. It also provides a list of all the changes made and the benefit of changing the code.

Make the application cloud native and deploy to AWS

The final step in the modernization journey is to make the application cloud-native and deploy to AWS. Cloud native is the software approach of building, deploying, and managing modern applications in cloud computing environments. These cloud native technologies support fast and frequent changes to applications without impacting service delivery, providing adopters with an innovative, competitive advantage. Let’s see how Amazon Q Developer can assist in making our Unicorn Store API project cloud native.

In IntelliJ IDE, open the Amazon Q Chat, and prompt Amazon Q Developer to provide a recommended approach to make the project cloud native and deploy to AWS.

In the IntelliJ IDE, user sends the content of the pom.xml file to Amazon Q Chat window, and asks Amazon Q Developer “What is the recommended way to make this micro service, cloud native and deploy to AWS?” Amazon Q generates the steps and a high-level implementation guide. In this case, it includes suggestions to containerize the application, use Amazon Elastic Container Registry, deploy to Amazon Elastic Container Service (ECS), implement a load balancer, leverage AWS Fargate, implement monitoring and logging, implement CI/CD, leverage other AWS managed services, implement security best practices, monitor and optimize the deployment.

Amazon Q Developer analyzes the code and details the steps involved in making this application cloud native. The detailed steps involve containerizing the application, deploying the container application to AWS services such as Amazon Elastic Container Service (Amazon ECS), Fargate for running containers in a serverless manner, Amazon Elastic Container Registry (Amazon ECR) for pushing the container image, accessing the application through AWS Application Load Balancer (ALB), Amazon CloudWatch for monitoring and associated services like Amazon Virtual Private Cloud (VPC) and Subnets.

Let’s ask Amazon Q Developer to implement the steps outlined in the previous chat conversation. First, ask Amazon Q Developer to create a docker file to containerize the application. The containerization process streamlines application development by decoupling the software from the underlying hardware and other dependencies. This approach enhances speed, efficiency, and security by isolating different components within the containerized environment.

In the IntelliJ IDE, user continues the conversation in the previous chat window. User asks Amazon Q Developer to provide implementation for the step 1 (containerize the application) and create a Dockefile for the application. Amazon Q generates a Dockerfile that includes all the necessary steps. User creates a new file named Dockerfile, and copies the contents from the chat window to the new file. Next, user opens the terminal within the IntelliJ IDE. User copies the build and run commands from the chat and pastes it in the terminal window. The application successfully builds in the docker container. Finally, application runs successfully as a docker container.

Having successfully developed a container-based application, let’s leverage Amazon Q Developer’s capabilities to generate an AWS CloudFormation template. This template will enable us to deploy the required resources to AWS using Infrastructure as Code (IaC). IaC allows us to programmatically provision and manage our computing infrastructure, eliminating the need for manual processes and configurations. Manual infrastructure management can be time-consuming and error-prone, especially when dealing with large-scale applications.

To facilitate the creation of the CloudFormation template, let’s revisit the suggestions from our previous conversation and compile a list of the resources that need to be provisioned in AWS. Once you have this list, you can ask Amazon Q Developer to generate the CloudFormation template based on these resource requirements.

In the IntelliJ IDE, user copies the steps outlined in the previous conversation, and asks Amazon Q Developer to create a CloudFormation template to deploy this application to AWS. Amazon Q Developer creates the full CloudFormation template to deploy all resources. User creates a new YAML file, and copies the contents from the chat window to the new file. The generated CloudFormation contains the steps to deploy VPCs, subnets, ECR, ECS cluster, Tasks, LoadBalancer, CloudWatch logs, etc. User reviews the generated code for accuracy before deployment.

Amazon Q Developer can generate the CloudFormation template with all the required resources as outlined in the steps to deploy the container in AWS in a secure, reliable, and scalable manner.

Now that we have the CloudFormation template, once CloudFormation is deployed, let’s push the local docker image of our Unicorn Store API to Amazon ECR and start the Fargate tasks required to run the application in AWS.

In the IntelliJ IDE, user runs the commands to push the docker image of the application created using Amazon Q Developer.

In this way, you can use Amazon Q Developer to make your application cloud native by designing the steps to deploy to the cloud, helping migrate your application to container-based solution and even writes Infrastructure as code scripts to deploy your application to AWS.

Conclusion

Amazon Q Developer empowers developers to simplify and accelerate the modernization of legacy Java applications. By leveraging Amazon Q Developer, developers can bring outdated applications up to current frameworks and deploy them to AWS in a cloud-native architecture. This streamlines the process, reducing the effort, risk, and maintenance required. Developers save significant time and resources, which can now be used to focus on building new features and enhancing modernized applications rather than managing technical debt.

To learn more about Amazon Q Developer, see the following resources:

Chetan Makvana

Chetan Makvana is a Senior Solutions Architect with Amazon Web Services. He works with AWS partners and customers to provide them with architectural guidance for building scalable architecture and implementing strategies to drive adoption of AWS services. He is a technology enthusiast and a builder with a core area of interest on generative AI, serverless, and DevOps. Outside of work, he enjoys watching shows, traveling, and music.

Venugopalan Vasudevan

Venugopalan Vasudevan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation. Venugopalan is dedicated to facilitating the Next Generation Developer experience, enabling developers to work more efficiently and creatively through the integration of Generative AI into their workflows.

Surabhi Tandon

Surabhi Tandon is a Senior Technical Account Manager at Amazon Web Services (AWS). She supports enterprise customers achieve operational excellence and help them with their cloud journey on AWS by providing strategic technical guidance. Surabhi is a builder with interest in Generative AI, automation, and DevOps. Outside of work, she enjoys hiking, reading and spending time with family and friends.

Enhance data security with fine-grained access controls in Amazon DataZone

Post Syndicated from Deepmala Agarwal original https://aws.amazon.com/blogs/big-data/enhance-data-security-with-fine-grained-access-controls-in-amazon-datazone/

Fine-grained access control is a crucial aspect of data security for modern data lakes and data warehouses. As organizations handle vast amounts of data across multiple data sources, the need to manage sensitive information has become increasingly important. Making sure the right people have access to the right data, without exposing sensitive information to unauthorized individuals, is essential for maintaining data privacy, compliance, and security.

Today, Amazon DataZone has introduced fine-grained access control, providing you granular control over your data assets in the Amazon DataZone business data catalog across data lakes and data warehouses. With the new capability, data owners can now restrict access to specific records of data at row and column levels, instead of granting access to the entire data asset. For example, if your data contains columns with sensitive information such as personally identifiable information (PII), you can restrict access to only the necessary columns, making sure sensitive information is protected while still allowing access to non-sensitive data. Similarly, you can control access at the row level, allowing users to see only the records that are relevant to their role or task.

In this post, we discuss how to implement fine-grained access control with row and column asset filters using this new feature in Amazon DataZone.

Row and column filters

Row filters enable you to restrict access to specific rows based on criteria you define. For instance, if your table contains data for two regions (America and Europe) and you want to make sure that employees in Europe only access data relevant to their region, you can create a row filter that excludes rows where the region is not Europe (for example, region != 'Europe'). This way, employees in America won’t have access to Europe’s data.

Column filters allow you to limit access to specific columns within your data assets. For example, if your table includes sensitive information such as PII, you can create a column filter to exclude PII columns. This makes sure subscribers can only access non-sensitive data.

The row and column asset filters in Amazon DataZone enable you to control who can access what using a consistent, business user-friendly mechanism for all of your data across AWS data lakes and data warehouses. To use fine-grained access control in Amazon DataZone, you can create row and column filters on top of your data assets in the Amazon DataZone business data catalog. When a user requests a subscription to your data asset, you can approve the subscription by applying the appropriate row and column filters. Amazon DataZone enforces these filters using AWS Lake Formation and Amazon Redshift, making sure the subscriber can only access the rows and columns that they are authorized to use.

Solution overview

To demonstrate the new capability, we consider a sample customer use case where an electronics ecommerce platform is looking to implement fine-grained access controls using Amazon DataZone. The customer has multiple product categories, each operated by different divisions of the company. The platform governance team wants to make sure each division has visibility only to data belonging to their own categories. Additionally, the platform governance team needs to adhere to the finance team requirements that pricing information should be visible only to the finance team.

The sales team, acting as the data producer, has published an AWS Glue table called Product sales that contains data for both Laptops and Servers categories to the Amazon DataZone business data catalog using the project Product-Sales. The analytic teams in both the laptop and server divisions need to access this data for their respective analytics projects. The data owner’s objective is to grant data access to consumers based on the division they belong to. This means giving access to only rows of data with laptop sales to the laptops sales analytics team, and rows with servers sales to the server sales analytics team. Additionally, the data owner wants to restrict both teams from accessing the pricing data. This post demonstrates the implementation steps to achieve this use case in Amazon DataZone.

The steps to configure this solution are as follows:

  1. The publisher creates asset filters for limiting access:
    1. We create two row filters: a Laptop Only row filter that limits access to only the rows of data with laptop sales, and a Server Only row filter that limits access to the rows of data with server sales.
    2. We also create a column filter called exclude-price-columns that excludes the price-related columns from the Product Sales
  2. Consumers discover and request subscriptions:
    1. The analyst from the laptops division requests a subscription to the Product Sales data asset.
    2. The analyst from the servers division also request a subscription to the Product Sales data asset.
    3. Both subscription requests are sent to the publisher for approval.
  3. The publisher approves the subscriptions and applies the appropriate filters:
    1. The publisher approves the request from the analysts in the laptops division, applying the Laptop Only row filter and the exclude-price-columns columns filter.
    2. The publisher approves the request from the consumer in the servers division, applying the Server Only row filter and the exclude-price-columns columns filter.
  4. Consumers access the authorized data in Amazon Athena:
    1. After the subscription is approved, we query the data in Athena to make sure that the analyst from the laptops division can now access only the product sales data for the Laptop
    2. Similarly, the analyst from the servers division can access only the product sales data for the Server
    3. Both consumers can see all columns except the price-related columns, as per the applied column filter.

The following diagram illustrates the solution architecture and process flow.

Prerequisites

To follow along with this post, the publisher of the product sales data asset must have published a sales dataset in Amazon DataZone.

Publisher creates asset filters for limiting access

In this section, we detail the steps the publisher takes to create asset filers.

Create row filters

This dataset contains the product categories Laptops and Servers. We want to restrict access to the dataset that is authorized based on the product category. We use the row filter feature in Amazon DataZone to achieve this.

Amazon DataZone allows you to create row filters that can be used when approving subscriptions to make sure that the subscriber can only access rows of data as defined in the row filters. To create a row filter, complete the following steps:

  1. On the Amazon DataZone console, navigate to the product-sales project (the project to which the asset belongs).
  2. Navigate to the Data tab for the project.
  3. Choose Inventory data in the navigation pane, then the asset Product Sales, where you want to create the row filter.

You can add row filters for assets of type AWS Glue tables or Redshift tables.

  1. On the asset detail page, on the Asset filters tab, choose Add asset filter.

We create two row filters, one each for the Laptops and Servers categories.

  1. Complete the following steps to create a laptop only asset row filter:
    1. Enter a name for this filter (Laptop Only).
    2. Enter a description of the filter (Allow rows with product category as Laptop Only).
    3. For the filter type, select Row filter.
    4. For the row filter expression, enter one or more expressions:
      1. Choose the column Product Category from the column dropdown menu.
      2. Choose the operator = from the operator dropdown menu.
      3. Enter the value Laptops in the Value field.
    5. If you need to add another condition to the filter expression, choose Add condition. For this post, we create a filter with one condition.
    6. When using multiple conditions in the row filter expression, choose And or Or to link the conditions.
    7. You can also define the subscriber visibility. For this post, we kept the default value (No, show values to subscriber).
    8. Choose Create asset filter.
  2. Repeat the same steps to create a row filter called Server Only, except this time enter the value Servers in the Value field.

Create column filters

Next, we create column filters to restrict access to columns with price-related data. Complete the following steps:

  1. In the same asset, add another asset filter of type column filter.
  2. On the Asset filters tab, choose Add asset filter.
  3. For Name, enter a name for the filter (for this post, exclude-price-columns).
  4. For Description, enter a description of the filters (for this post, exclude price data columns).
  5. For the filter type, select Column to create the column filter. This will display all the available columns in the data asset’s schema.
  6. Select all columns except the price-related ones.
  7. Choose Create asset filter.

Consumers discover and request subscriptions

In this section, we switch to the role of an analyst from the laptop division who is working within the project Sales Analytics - Laptop. As the data consumer, we search the catalog to find the Product Sales data asset and request access by subscribing to it.

  1. Log in to your project as a consumer and search for the Product Sales data asset.
  2. On the Product Sales data asset details page, choose Subscribe.
  3. For Project, choose Sales Analytics – Laptops.
  4. For Reason for request, enter the reason for the subscription request.
  5. Choose Subscribe to submit the subscription request.

Publisher approves subscriptions with filters

After the subscription request is submitted, the publisher will receive the request, and they can approve it by following these steps:

  1. As the publisher, open the project Product-Sales.
  2. On the Data tab, choose Incoming requests in the left navigation pane.
  3. Locate the request and choose View request. You can filter by Pending to see only requests that are still open.

This opens the details of the request, where you can see details like who requested the access, for what project, and the reason for the request.

  1. To approve the request, there are two options:
    1. Full access – If you choose to approve the subscription with full access option, the subscriber will get access to all the rows and columns in our data asset.
    2. Approve with row and column filters – To limit access to specific rows and columns of data, you can choose the option to approve with row and column filters. For this post, we use both filters that we created earlier.
  2. Select Choose filter, then on the dropdown menu, choose the Laptops Only and pii-col-filter
  3. Choose Approve to approve the request.

After access is granted and fulfilled, the subscription looks as shown in the following screenshot.

  1. Now let’s log in as a consumer from the server division.
  2. Repeat the same steps, but this time, while approving the subscription, the publisher of sales data approves with the Server only The other steps remain the same.

Consumers access authorized data in Athena

Now that we have successfully published an asset to the Amazon DataZone catalog and subscribed to it, we can analyze it. Let’s log in as a consumer from the laptop division.

  1. In the Amazon DataZone data portal, choose the consumer project Sales Analytics - Laptops.
  2. On the Schema tab, we can view the subscribed assets.
  3. Choose the project Sales Analytics - Laptops and choose the Overview
  4. In the right pane, open the Athena environment.

We can now run queries on the subscribed table.

  1. Choose the table under Tables and views, then choose Preview to view the SELECT statement in the query editor.
  2. Run a query as the consumer of Sales Analytics - Laptops, in which we can view data only with product category Laptops.

Under Tables and views, you can expand the table product_sales. The price-related columns are not visible in the Athena environment for querying.

  1. Next, you can switch to the role of analyst from the server division and analyze the dataset in similar way.
  2. We run the same query and see that under product_category, the analyst can see Servers only.

Conclusion

Amazon DataZone offers a straightforward way to implement fine-grained access controls on top of your data assets. This feature allows you to define column-level and row-level filters to enforce data privacy before the data is available to data consumers. Amazon DataZone fine-grained access control is generally available in all AWS Regions that support Amazon DataZone.

Try out the fine-grained access control feature in your own use case, and let us know your feedback in the comments section.


About the Authors

Deepmala Agarwal works as an AWS Data Specialist Solutions Architect. She is passionate about helping customers build out scalable, distributed, and data-driven solutions on AWS. When not at work, Deepmala likes spending time with family, walking, listening to music, watching movies, and cooking!
Leonardo Gomez is a Principal Analytics Specialist Solutions Architect at AWS. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs. Connect with him on LinkedIn.

Utkarsh Mittal is a Senior Technical Product Manager for Amazon DataZone at AWS. He is passionate about building innovative products that simplify customers’ end-to-end analytics journeys. Outside of the tech world, Utkarsh loves to play music, with drums being his latest endeavor.
Automate data loading from your database into Amazon Redshift using AWS Database Migration Service (DMS), AWS Step Functions, and the Redshift Data API

Post Syndicated from Ritesh Sinha original https://aws.amazon.com/blogs/big-data/automate-data-loading-from-your-database-into-amazon-redshift-using-aws-database-migration-service-dms-aws-step-functions-and-the-redshift-data-api/

Amazon Redshift is a fast, scalable, secure, and fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing ETL (extract, transform, and load), business intelligence (BI), and reporting tools. Tens of thousands of customers use Amazon Redshift to process exabytes of data per day and power analytics workloads such as BI, predictive analytics, and real-time streaming analytics.

As more and more data is being generated, collected, processed, and stored in many different systems, making the data available for end-users at the right place and right time is a very important aspect for data warehouse implementation. A fully automated and highly scalable ETL process helps minimize the operational effort that you must invest in managing the regular ETL pipelines. It also provides timely refreshes of data in your data warehouse.

You can approach the data integration process in two ways:

  • Full load – This method involves completely reloading all the data within a specific data warehouse table or dataset
  • Incremental load – This method focuses on updating or adding only the changed or new data to the existing dataset in a data warehouse

This post discusses how to automate ingestion of source data that changes completely and has no way to track the changes. This is useful for customers who want to use this data in Amazon Redshift; some examples of such data are products and bills of materials without tracking details at the source.

We show how to build an automatic extract and load process from various relational database systems into a data warehouse for full load only. A full load is performed from SQL Server to Amazon Redshift using AWS Database Migration Service (AWS DMS). When Amazon EventBridge receives a full load completion notification from AWS DMS, ETL processes are run on Amazon Redshift to process data. AWS Step Functions is used to orchestrate this ETL pipeline. Alternatively, you could use Amazon Managed Workflows for Apache Airflow (Amazon MWAA), a managed orchestration service for Apache Airflow that makes it straightforward to set up and operate end-to-end data pipelines in the cloud.

Solution overview

The workflow consists of the following steps:

  1. The solution uses an AWS DMS migration task that replicates the full load dataset from the configured SQL Server source to a target Redshift cluster in a staging area.
  2. AWS DMS publishes the replicationtaskstopped event to EventBridge when the replication task is complete, which invokes an EventBridge rule.
  3. EventBridge routes the event to a Step Functions state machine.
  4. The state machine calls a Redshift stored procedure through the Redshift Data API, which loads the dataset from the staging area to the target production tables. With this API, you can also access Redshift data with web-based service applications, including AWS Lambda.

The following architecture diagram highlights the end-to-end solution using AWS services.

In the following sections, we demonstrate how to create the full load AWS DMS task, configure the ETL orchestration on Amazon Redshift, create the EventBridge rule, and test the solution.

Prerequisites

To complete this walkthrough, you must have the following prerequisites:

  • An AWS account
  • A SQL Server database configured as a replication source for AWS DMS
  • A Redshift cluster to serve as the target database
  • An AWS DMS replication instance to migrate data from source to target
  • A source endpoint pointing to the SQL Server database
  • A target endpoint pointing to the Redshift cluster

Create the full load AWS DMS task

Complete the following steps to set up your migration task:

  1. On the AWS DMS console, choose Database migration tasks in the navigation pane.
  2. Choose Create task.
  3. For Task identifier, enter a name for your task, such as dms-full-dump-task.
  4. Choose your replication instance.
  5. Choose your source endpoint.
  6. Choose your target endpoint.
  7. For Migration type, choose Migrate existing data.

  1. In the Table mapping section, under Selection rules, choose Add new selection rule
  2. For Schema, choose Enter a schema.
  3. For Schema name, enter a name (for example, dms_sample).
  4. Keep the remaining settings as default and choose Create task.

The following screenshot shows your completed task on the AWS DMS console.

Create Redshift tables

Create the following tables on the Redshift cluster using the Redshift query editor:

  • dbo.dim_cust – Stores customer attributes:
CREATE TABLE dbo.dim_cust (
cust_key integer ENCODE az64,
cust_id character varying(10) ENCODE lzo,
cust_name character varying(100) ENCODE lzo,
cust_city character varying(50) ENCODE lzo,
cust_rev_flg character varying(1) ENCODE lzo
)

DISTSTYLE AUTO;
  • dbo.fact_sales – Stores customer sales transactions:
CREATE TABLE dbo.fact_sales (
order_number character varying(20) ENCODE lzo,
cust_key integer ENCODE az64,
order_amt numeric(18,2) ENCODE az64
)

DISTSTYLE AUTO;
  • dbo.fact_sales_stg – Stores daily customer incremental sales transactions:
CREATE TABLE dbo.fact_sales_stg (
order_number character varying(20) ENCODE lzo,
cust_id character varying(10) ENCODE lzo,
order_amt numeric(18,2) ENCODE az64
)

DISTSTYLE AUTO;

Use the following INSERT statements to load sample data into the sales staging table:

insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (100,1,200);
insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (101,1,300);
insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (102,2,25);
insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (103,2,35);
insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (104,3,80);
insert into dbo.fact_sales_stg(order_number,cust_id,order_amt) values (105,3,45);

Create the stored procedures

In the Redshift query editor, create the following stored procedures to process customer and sales transaction data:

  • Sp_load_cust_dim() – This procedure compares the customer dimension with incremental customer data in staging and populates the customer dimension:
CREATE OR REPLACE PROCEDURE dbo.sp_load_cust_dim()
LANGUAGE plpgsql
AS $$
BEGIN
truncate table dbo.dim_cust;
insert into dbo.dim_cust(cust_key,cust_id,cust_name,cust_city) values (1,100,'abc','chicago');
insert into dbo.dim_cust(cust_key,cust_id,cust_name,cust_city) values (2,101,'xyz','dallas');
insert into dbo.dim_cust(cust_key,cust_id,cust_name,cust_city) values (3,102,'yrt','new york');
update dbo.dim_cust
set cust_rev_flg=case when cust_city='new york' then 'Y' else 'N' end
where cust_rev_flg is null;
END;
$$
  • sp_load_fact_sales() – This procedure does the transformation for incremental order data by joining with the date dimension and customer dimension and populates the primary keys from the respective dimension tables in the final sales fact table:
CREATE OR REPLACE PROCEDURE dbo.sp_load_fact_sales()
LANGUAGE plpgsql
AS $$
BEGIN
--Process Fact Sales
insert into dbo.fact_sales
select
sales_fct.order_number,
cust.cust_key as cust_key,
sales_fct.order_amt
from dbo.fact_sales_stg sales_fct
--join to customer dim
inner join (select * from dbo.dim_cust) cust on sales_fct.cust_id=cust.cust_id;
END;
$$

Create the Step Functions state machine

Complete the following steps to create the state machine redshift-elt-load-customer-sales. This state machine is invoked as soon as the AWS DMS full load task for the customer table is complete.

  1. On the Step Functions console, choose State machines in the navigation pane.
  2. Choose Create state machine.
  3. For Template, choose Blank.
  4. On the Actions dropdown menu, choose Import definition to import the workflow definition of the state machine.

  1. Open your preferred text editor and save the following code as an ASL file extension (for example, redshift-elt-load-customer-sales.ASL). Provide your Redshift cluster ID and the secret ARN for your Redshift cluster.
{
"Comment": "State Machine to process ETL for Customer Sales Transactions",
"StartAt": "Load_Customer_Dim",
"States": {
"Load_Customer_Dim": {
"Type": "Task",
"Parameters": {
"ClusterIdentifier": "redshiftcluster-abcd",
"Database": "dev",
"Sql": "call dbo.sp_load_cust_dim()",
"SecretArn": "arn:aws:secretsmanager:us-west-2:xxx:secret:rs-cluster-secret-abcd"
},
"Resource": "arn:aws:states:::aws-sdk:redshiftdata:executeStatement",
"Next": "Wait on Load_Customer_Dim"
},
"Wait on Load_Customer_Dim": {
"Type": "Wait",
"Seconds": 30,
"Next": "Check_Status_Load_Customer_Dim"
},

"Check_Status_Load_Customer_Dim": {
"Type": "Task",
"Next": "Choice",
"Parameters": {
"Id.$": "$.Id"
},

"Resource": "arn:aws:states:::aws-sdk:redshiftdata:describeStatement"
},

"Choice": {
"Type": "Choice",
"Choices": [
{
"Not": {
"Variable": "$.Status",
"StringEquals": "FINISHED"
},
"Next": "Wait on Load_Customer_Dim"
}
],
"Default": "Load_Sales_Fact"
},
"Load_Sales_Fact": {
"Type": "Task",
"End": true,
"Parameters": {
"ClusterIdentifier": "redshiftcluster-abcdef”,
"Database": "dev",
"Sql": "call dbo.sp_load_fact_sales()",
"SecretArn": "arn:aws:secretsmanager:us-west-2:xxx:secret:rs-cluster-secret-abcd"
},

"Resource": "arn:aws:states:::aws-sdk:redshiftdata:executeStatement"
}
}
}
  1. Choose Choose file and upload the ASL file to create a new state machine.

  1. For State machine name, enter a name for the state machine (for example, redshift-elt-load-customer-sales).
  2. Choose Create.

After the successful creation of the state machine, you can verify the details as shown in the following screenshot.

The following diagram illustrates the state machine workflow.

The state machine includes the following steps:

  • Load_Customer_Dim – Performs the following actions:
    • Passes the stored procedure sp_load_cust_dim to the execute-statement API to run in the Redshift cluster to load the incremental data for the customer dimension
    • Sends data back the identifier of the SQL statement to the state machine
  • Wait_on_Load_Customer_Dim – Waits for at least 15 seconds
  • Check_Status_Load_Customer_Dim – Invokes the Data API’s describeStatement to get the status of the API call
  • is_run_Load_Customer_Dim_complete – Routes the next step of the ETL workflow depending on its status:
    • FINISHED – Passes the stored procedure Load_Sales_Fact to the execute-statement API to run in the Redshift cluster, which loads the incremental data for fact sales and populates the corresponding keys from the customer and date dimensions
    • All other statuses – Goes back to the wait_on_load_customer_dim step to wait for the SQL statements to finish

The state machine redshift-elt-load-customer-sales loads the dim_cust, fact_sales_stg, and fact_sales tables when invoked by the EventBridge rule.

As an optional step, you can set up event-based notifications on completion of the state machine to invoke any downstream actions, such as Amazon Simple Notification Service (Amazon SNS) or further ETL processes.

Create an EventBridge rule

EventBridge sends event notifications to the Step Functions state machine when the full load is complete. You can also turn event notifications on or off in EventBridge.

Complete the following steps to create the EventBridge rule:

  1. On the EventBridge console, in the navigation pane, choose Rules.
  2. Choose Create rule.
  3. For Name, enter a name (for example, dms-test).
  4. Optionally, enter a description for the rule.
  5. For Event bus, choose the event bus to associate with this rule. If you want this rule to match events that come from your account, select AWS default event bus. When an AWS service in your account emits an event, it always goes to your account’s default event bus.
  6. For Rule type, choose Rule with an event pattern.
  7. Choose Next.
  8. For Event source, choose AWS events or EventBridge partner events.
  9. For Method, select Use pattern form.
  10. For Event source, choose AWS services.
  11. For AWS service, choose Database Migration Service.
  12. For Event type, choose All Events.
  13. For Event pattern, enter the following JSON expression, which looks for the REPLICATON_TASK_STOPPED status for the AWS DMS task:
{
"source": ["aws.dms"],
"detail": {
"eventId": ["DMS-EVENT-0079"],
"eventType": ["REPLICATION_TASK_STOPPED"],
"detailMessage": ["Stop Reason FULL_LOAD_ONLY_FINISHED"],
"type": ["REPLICATION_TASK"],
"category": ["StateChange"]
}
}

  1. For Target type, choose AWS service.
  2. For AWS service, choose Step Functions state machine.
  3. For State machine name, enter redshift-elt-load-customer-sales.
  4. Choose Create rule.

The following screenshot shows the details of the rule created for this post.

Test the solution

Run the task and wait for the workload to complete. This workflow moves the full volume data from the source database to the Redshift cluster.

The following screenshot shows the load statistics for the customer table full load.

AWS DMS provides notifications when an AWS DMS event occurs, for example the completion of a full load or if a replication task has stopped.

After the full load is complete, AWS DMS sends events to the default event bus for your account. The following screenshot shows an example of invoking the target Step Functions state machine using the rule you created.

We configured the Step Functions state machine as a target in EventBridge. This enables EventBridge to invoke the Step Functions workflow in response to the completion of an AWS DMS full load task.

Validate the state machine orchestration

When the entire customer sales data pipeline is complete, you may go through the entire event history for the Step Functions state machine, as shown in the following screenshots.

Limitations

The Data API and Step Functions AWS SDK integration offers a robust mechanism to build highly distributed ETL applications within minimal developer overhead. Consider the following limitations when using the Data API and Step Functions:

Clean up

To avoid incurring future charges, delete the Redshift cluster, AWS DMS full load task, AWS DMS replication instance, and Step Functions state machine that you created as part of this post.

Conclusion

In this post, we demonstrated how to build an ETL orchestration for full loads from operational data stores using the Redshift Data API, EventBridge, Step Functions with AWS SDK integration, and Redshift stored procedures.

To learn more about the Data API, see Using the Amazon Redshift Data API to interact with Amazon Redshift clusters and Using the Amazon Redshift Data API.


About the authors

Ritesh Kumar Sinha is an Analytics Specialist Solutions Architect based out of San Francisco. He has helped customers build scalable data warehousing and big data solutions for over 16 years. He loves to design and build efficient end-to-end solutions on AWS. In his spare time, he loves reading, walking, and doing yoga.

Praveen Kadipikonda is a Senior Analytics Specialist Solutions Architect at AWS based out of Dallas. He helps customers build efficient, performant, and scalable analytic solutions. He has worked with building databases and data warehouse solutions for over 15 years.

Jagadish Kumar (Jag) is a Senior Specialist Solutions Architect at AWS focused on Amazon OpenSearch Service. He is deeply passionate about Data Architecture and helps customers build analytics solutions at scale on AWS.

Serverless ICYMI Q2 2024

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/serverless-icymi-q2-2024/

Welcome to the 26th edition of the AWS Serverless ICYMI (in case you missed it) quarterly recap. Every quarter, we share all the most recent product launches, feature enhancements, blog posts, webinars, live streams, and other interesting things that you might have missed!

In case you missed our last ICYMI, check out what happened last quarter here.

Calendar

Calendar

EDA Day – London 2024

The AWS Serverless DA team hosted the third Event-Driven Architecture (EDA) Day in London on May 14th. This event brought together prominent figures in the event-driven architecture community, AWS, and customer speakers.

EDA Day covered 13 sessions, 2 workshops, and a Q&A panel. David Boyne was the keynote speaker with a talk “Complexity is the Gotcha of Event-Driven Architecture”. There were AWS speakers including Matthew Meckes, Natasha Wright, Julian Wood, Gillian Amstrong, Josh Kahn, Veda Ramen, and Uma Ramadoss. There was also an impressive lineup of guest speakers, Daniele Frasca, David Anderson, Ryan Cormack, Sarah Hamilton, Sheen Brisals, Marcin Sodkiewicz, and Ben Ellerby.

Videos are available on YouTube

EDA Day London

EDA Day London

The future of Serverless

There has been a lot of talk about the future of serverless, with this year being the 10th anniversary of AWS Lambda. Eric Johnson addresses the topic in his ServerlessDays Milan keynote, “Now serverless is all grown up, what’s next”.

AWS Lambda

AWS launched support for the latest release of Ruby 3.3 is based on the new Amazon Linux 2023 runtime. The Ruby 3.3 runtime also provides access to the latest Ruby language features.

There is a new guide on how to retrieve data about Lambda functions that use a deprecated runtime.

Learn how to run code after returning a response from an AWS Lambda function. This post shows how to return a synchronous function response as soon as possible, yet also perform additional asynchronous work after you send the response. For example, you may store data in a database or send information to a logging system.

See how you can use the circuit-breaker pattern with Lambda extensions and Amazon DynamoDB. The circuit breaker pattern can help prevent cascading failures and improve overall system stability.

Circuit-breaker pattern

Circuit-breaker pattern

Lambda functions now scale up to 12X faster in the AWS GovCloud (US) Regions.

Powertools for AWS Lambda (Python) adds support for Agents for Amazon Bedrock.

The AWS SDK for JavaScript v2 enters maintenance mode on September 8, 2024 and reaches end-of-support on September 8, 2025.

Amazon CloudWatch Logs introduced Live Tail streaming CLI support.

Amazon ECS and AWS Fargate

You can now secure Amazon Elastic Container Service (Amazon ECS) workloads on AWS Fargate with customer managed keys (CMKs). Once you add your keys to AWS Key Management Service (AWS KMS), you can use these to encrypt the underlying ephemeral storage of an Amazon ECS task on AWS Fargate.

Windows containers on AWS Fargate now start faster, up to 42% for Windows Server 2022 Core. AWS has optimized the Windows Server AMIs, introduced EC2 fast launch with pre-provisioned snapshots, and reduced network latency.

Amazon ECS Service Connect is a networking capability to simplify service discovery, connectivity, and traffic observability for Amazon ECS. You can now proactively scale Amazon ECS services by using custom metrics.

ECS Connect custom metrics

ECS Service Connect custom metrics

AWS Step Functions

The AWS Step Functions TestState API allows you to test individual states independently and to integrate testing into your preferred development workflows. Learn how to accelerate workflow development to iterate faster.

Step Functions TestState API

Step Functions TestState API

Amazon EventBridge

Amazon EventBridge Pipes now supports event delivery through AWS PrivateLink. You can send events from an event source located in an Amazon Virtual Private Cloud (VPC) to a Pipes target without traversing the public internet.

Amazon Timestream for LiveAnalytics is now an EventBridge Pipes target. Timestream for LiveAnalytics is a fast, scalable, purpose-built time series database that makes it easy to store and analyze trillions of time series data points per day.

EventBridge has a new console dashboard which provides a centralized view of your resources, metrics, and quotas. The console has an improved Learn page and other console enhancements. When using the CloudFormation template export for Pipes, you can also generate the IAM role. There is a new Rules tab in the Event Bus detail page, and the monitoring tab in the Rule detail page now includes additional metrics.

EventBridge Scheduler has some new API request metrics for improved observability.

Generative AI

Amazon Bedrock is a fully managed Generative AI service that offers a choice of high-performing foundation models (FMs) from leading AI companies through a single API. Bedrock now supports new models, including Anthropic’s Claude 3.5, AI21 Labs’ Jamba-Instruct, Amazon Titan Text Premier.

The new Bedrock Converse API provides a consistent way to invoke Amazon Bedrock models and simplifies multi-turn conversations. There is also a JavaScript tutorial to walk you through sending requests to the Converse API using the Javascript SDK.

Amazon Q Developer is now generally available. Amazon Q Developer, part of the Amazon Q family, is a generative AI–powered assistant for software development. Amazon Q is available in the AWS Management Console and as an integrated development environment (IDE) extension for Visual Studio Code, Visual Studio, and JetBrains IDEs. Amazon Q Developer has knowledge of your AWS account resources and can help understand your costs.

Amazon Q list Lambda functions

Amazon Q list Lambda functions

You can use Amazon Q Developer to develop code features and transform code to upgrade Java applications. Amazon Q Developer also offers inline completions in the command line. For more information, see Reimagining software development with the Amazon Q Developer Agent.

Amazon Q code features

Amazon Q code features

Knowledge Bases for Amazon Bedrock now let you configure Guardrails, configure inference parameters, and offers observability logs.

Storage and data

Amazon S3 no longer charges for several HTTP error codes if initiated from outside your individual AWS account or AWS Organization.

You can automatically detect malware in new object uploads to S3 with Amazon GuardDuty.

Amazon Elastic File System (Amazon EFS) now support up to 1.5 GiB/s of throughput per client, a 3x increase over the previous limit of 500 MiB/s.

Discover architectural patterns for real-time analytics using Amazon Kinesis Data Streams in part 1 and part 2 and see how to optimize write throughput.

Amazon API Gateway

Amazon API Gateway now allows you to increase the integration timeout beyond the prior limit of 29 seconds. You can raise the integration timeout for Regional and private REST APIs, but this might require a reduction in your account-level throttle quota limit. This launch can help with workloads that require longer timeouts, such as Generative AI use cases with Large Language Models (LLMs).

You can also now use Amazon Verified Permissions to secure API Gateway REST APIs when using an Open ID connect (OIDC) compliant identity provider. You can now control access based on user attributes and group memberships, without writing code.

AWS AppSync

You can now invoke your AWS AppSync data sources in an event-driven manner. Previously, you could only invoke Lambda functions synchronously from AWS AppSync. AWS AppSync can now trigger Lambda functions in Event mode, asynchronously decoupling the API response from the Lambda invocation, which helps with long-running operations.

AWS AppSync now passes application request headers to Lambda custom authorizer functions. You can make authorization decisions based on the value of the authorization header, and the value of other headers that were sent with the request from the application client.

Learn best practices for AWS AppSync GraphQL APIs. See how to how to optimize the security, performance, coding standards, and deployment of your AWS AppSync API. AWS AppSync also has increase quotas, and new metrics

AWS Amplify

AWS Amplify Gen 2 is now generally available. This now provides a code-first developer experience for building full-stack apps using TypeScript. Amplify Gen 2 allows you to express app requirements like the data models, business logic, and authorization rules in TypeScript.

AWS Amplify Gen2

AWS Amplify Gen2

Amplify has a new experience for file storage. This post explores using Lambda to create serverless functions for Amplify using TypeScript. There are also new team environment workflows.

Serverless blog posts

April

May

June

Serverless container blog posts

April

May

June

Serverless Office Hours

Serverless Office Hours

Serverless Office Hours

April

May

June

Containers from the Couch

Containers from the Couch

Containers from the Couch

April

May

FooBar Serverless

April

February

June

Still looking for more?

The Serverless landing page has more information. The Lambda resources page contains case studies, webinars, whitepapers, customer stories, reference architectures, and even more Getting Started tutorials.

You can also follow the Serverless Developer Advocacy team on X (formerly Twitter) to see the latest news, follow conversations, and interact with the team.

And finally, visit the Serverless Land and Containers on AWS websites for all your serverless and serverless container needs.

Трябва ли неправославните да се интересуват от БПЦ?

Post Syndicated from Светла Енчева original https://www.toest.bg/tryabva-li-nepravoslavnite-da-se-interesuvat-ot-bpts/

Трябва ли неправославните да се интересуват от БПЦ?

В края на миналата седмица Българската православна църква (БПЦ) избра свой патриарх – за втори път от 1989 г. насам. Изборът се превърна във водеща тема и беше подробно отразен в медиите. Когато стана ясно, че новият патриарх ще е Даниил Видински, последваха бурни реакции. Поводът за тях беше, че той нееднократно е изразявал проруски позиции.

Ала не е ли редно само вярващите и практикуващи православни християни да имат право на мнение по темата? Ако не се интересувате от футбол, какво значение има за вас дали отборът на България се е класирал за Европейското първенство или кой ще стане европейски шампион по футбол?

Ако Църквата и държавата бяха наистина отделени, както е по конституция, ако религията не се използваше за политически цели и БПЦ не оказваше влияние върху живота на непринадлежащите към нея, тогава действително православните християни щяха да имат най-голямо право да я критикуват. Така ли е обаче?

Ролята на БПЦ в политическия и обществения живот

Освен религиозно събитие, избирането на патриарх Даниил беше и политическо. На първо място, защото е залог в борбата за външнополитическата ориентация на България. На първата литургия с негово участие присъстваха редица проруски политици, например Румен Петков и бившият президент Георги Първанов, както и руската посланичка Елеонора Митрофанова.

Значението на БПЦ за външната политика е голямо заради все по-нарастващата ѝ роля във вътрешнополитическия и обществения живот през последния четвърт век. През 2001 г., когато на власт идва Симеон Сакскобургготски, патриархът за първи път влиза в Народното събрание за откриването му. И с малки изключения получава запазено място там. Докато се стигне до наши дни, когато президентът поздравява новоизбрания предводител на БПЦ с думите „Бог да пази България“, а встъпването му в длъжност се отбелязва дори с военни почести.

Православнообразната реторика, на която практически никой политик не се противопоставя, служи и за политически послания и обосноваване на политически решения. Откриването на предишното 49-то Народно събрание например беше съпроводено с нещо като сапунена миниопера, понеже се случи в Страстната седмица. И кой ли не сметна за нужно да направи връзка между страстите Христови и политическия живот в България – от президента, през председателя на ГЕРБ Бойко Борисов, та до тогавашния главен прокурор Иван Гешев.

За доминирането на БПЦ в обществения живот услужливо допринасят и голяма част от медиите. Ако има православен празник или важно църковно събитие, почти целите новинарски емисии на водещите телевизии се запълват с него. Дори медии, които се стремят да спазват журналистическите стандарти, понякога губят критична дистанция и забравят за мисията си да обясняват какво се случва. И започват да говорят на църковен език – например как Даниил Видински бил „възведен в архимандритско достойнство“ и „хиротонисан за епископ“. Вместо простичко да кажат: „станал архимандрит“, „ръкоположен за епископ“.

На БПЦ обаче настоящата сериозна роля в обществено-политическия живот не ѝ е достатъчна. Едни от първите думи на новоизбрания патриарх Даниил бяха, че училищният предмет религия и православие трябва да стане задължителен. А който не е православен, можело да учи други религии, етика или философия. Понастоящем религията се изучава факултативно, а предметите етика и философия са в учебния план на гимназиите още от началото на 90-те. Така че не е ясно в какво точно би се изразила исканата от патриарха промяна. Ясно е само, че иска да е задължително.

Намесата на религията в правото на личен живот

Православието влияе и върху личния живот дори на хората, които не са православни. Медиите не пропускат да ни напомнят кога според православния календар трябва да празнуваме, да скърбим, да се смирим или да се извиняваме. И че трябва да почитаме починалите си близки точно на Задушница, а не на някоя дата, която лично на нас ни е важна.

Но докато несъобразяването с тези ритуали се възприема като морално прегрешение или най-малкото като социална неадекватност, има сфери, в които религията е допусната – и то от възможно най-високите места в държавата – да реши вместо нас как да живеем живота си. Позицията на БПЦ, както и на други християнски деноминации се взема под внимание и в законодателния процес, служи като аргумент и за решения на върховните съдилища.

И макар другите християнски деноминации да са особено гласовити, когато става въпрос за ограничаване на правото на личен живот, никой не би им обърнал внимание, ако не действаха в унисон с БПЦ, националистическите партии и руската пропаганда.

Дори да не сте религиозни, държавата може да ви забрани да сключите брак с аргумента, че това противоречи на традициите и религията в България. По-точно, противоречи на Конституцията, според задължителните тълкувания на която тя е в съответствие с религията и традициите (независимо какво пише в самата Конституция). Попадате в горната хипотеза, ако обичате човек от същия пол. Пак в името на религията и традициите държавата няма да ви разреши и друга форма на регистрирано партньорство с любимия човек, въпреки че според Европейския съд по правата на човека тя е длъжна да го направи – поне за сключилите брак в чужбина.

Религията и традициите имат думата и какво име и какъв пол да пише в документите ви за самоличност. Не в кръщелното ви свидетелство, а в гражданските ви документи. Ако сте от късметлийското мнозинство, членовете на което се идентифицират в съответствие с половите си органи, нямате проблем. Но ако имате външните белези на мъж, а се чувствате като жена или обратното, не сте достатъчно традиционни и религиозно приемливи. И сте осъдени на доживотен тормоз и присмех, когато някой погледне първо личната ви карта, а после вас (или обратното).

Много имоти, никакви данъци

Но да допуснем, че сте хетеросексуални, не сте трансджендър и не се интересувате от политика – нито вътрешна, нито външна. Дори и в този случай БПЦ влияе върху живота ви. Посредством парите във вашия джоб.

Колко имота притежава Църквата, никой простосмъртен не знае. По всяка вероятност те струват милиарди, както показва разследване на bTV. Не става дума само за църкви, параклиси и манастири. БПЦ притежава например луксозни магазини и заведения в идеалния център на София, парцели в доста столични квартали, както и жилищни сгради. И си строи цял комплекс на територията на „Манастирски ливади“.

Не само за имотите, но и за печалбите от наеми и продажби Църквата не плаща данъци, макар че на теория дължи данъци върху печалбата от търговска дейност. Защото ги интерпретира като… дарения от вярващи. А държавата не си и поставя за цел да съпостави тази интерпретация със закона. Така в бюджета не влизат (може би) милиони. А печалбите отиват неизвестно къде.

Видно е обаче къде не отиват. Не отиват за ремонт на църкви и манастири в окаяно състояние, за чието спасяване се събират дарения. Още по-малко отиват за подпомагане на нуждаещите се. БПЦ не изглежда да осъзнава, че Църквата би следвало да има и социална функция, каквато имат християнските църкви на много места по света.

БПЦ не плаща данъци на държавата, но пък държавата плаща на Църквата. За заплати на свещеници, че и за изграждане на църкви. В разследването на bTV Горан Благоев твърди, че в държавния бюджет за 2024 г. перото за Църквата е 38,4 млн. лв. Той поставя въпроса за липсващата социална дейност на Църквата и пита: „Трябва ли държавата да налива пари в институция, която не изпълнява обществената си функция?“

Благоев беше водещ на предаването „Вяра и общество“ по БНТ, но в резултат на критичната му позиция към БПЦ предаването беше свалено. Това е впрочем още един случай, когато държавата застава на страната на Църквата, а не на гражданите си.

България още ли е светска?

През 2017 г. журналистката Татяна Ваксберг попита: „България не беше ли светска?“ Седем години по-късно този въпрос все повече прилича на табу. Той не се поставя (както отбелязва Ваксберг още преди десет години). Ако някой се подлъже да го зададе, следва мълчание. В същото време ролята на религията в публичния живот расте. Тоест не на православието само по себе си, а на определени негови политически интерпретации.

Това е обидно и за някои вярващи, които виждат как с религията им се злоупотребява. Нерелигиозните и изповядващите религии, различни от християнството, обаче проявяват завидна търпимост към прогресивното стесняване на светското поле в публичния живот. Или по-скоро непукизъм.

Срастването на държавата и Църквата в България е проблем не само на ЛГБТИ+ хората, които не могат да сключат брак или да сменят гражданския си пол. По един или друг начин то е проблем на всички. И ще става все по-голям. Освен за онези, които прибират печалбата. И финансовата, и политическата.

На север: Острови от вълна сред вълните на Атлантика (първа част)

Post Syndicated from Светла Стоянова original https://www.toest.bg/na-sever-ostrovi-ot-vulna-sred-vulnitie-na-atlantika-purva-chast/

Пристигнахме в пълна тъмница, мокър, хладен вятър ни забрули за добре дошли. Разпънахме палатката на една прогизнала поляна и се заслушахме в неравномерното барабанене на капките по платното. Вече на сухо и в топлия спален чувал, дъждът ми се струваше като нежна приспивна песен. Сутринта, щом дръпнах ципа на вратичката, слънчев лъч проблесна в очите ми и за първи път осъзнах къде се намираме. Пред мен се ширеше синият океан и от него бяха изникнали няколко яркозелени острова, стръмни като планини. Полярни буревестници плавно се спускаха, почти докосваха водната повърхност, плъзгаха се на сантиметри от нея и наново се издигаха с все същата грация. В далечината пориви на вятъра оставяха следите си в морето, сякаш нещо невидимо близваше водата и я разнасяше на хиляди малки капчици във въздуха. Бях тук, чувствах мократа трева по пръстите си и знаех, че не е видение.

На север: Острови от вълна сред вълните на Атлантика (първа част)

Два пъти имах късмета да посетя Фарьорските острови и да палаткувам на шест от тях в два различни сезона. Но не си представяйте екзотични дестинации като Канарските или Карибските острови, а по-скоро архипелаг, брулен от северноатлантическия вятър някъде между Норвегия, Шотландия и Исландия. Осемнайсетте острова са с разнообразен релеф, някои – със стръмни зелени поляни и отвесни базалтови скали, а други – разчленени от фиорди, каменисти заливи и черни плажове, неуморно изложени на шлифоването на соления океан. Въпреки това почти всички са обитаеми. От хиляди овце, хора, диви зайци и птици – всички те изложени на произвола на времето и милостта на океана.

Името на островите означава „острови на овцете“, при това с право, защото и до днес животните са почти два пъти повече от населението.

През цялата година овцете пасат навън, тъй като естествени хищници на островите няма, а вълната им ги пази от студа и вятъра благодарение на високото си съдържание на ланолин – мазен секрет по вълнените влакна, който я прави водоустойчива. Това е една от най-топлите вълни в света и стара местна поговорка гласи: Ull er Føroya gull (Вълната е фарьорското злато).

На север: Острови от вълна сред вълните на Атлантика (първа част)
Фарьорски овце през май © Светла Стоянова

В продължение на векове сръчните фарьорски ръце са я обработвали, а след това изплитали топли пуловери с характерни местни шарки, дебели чорапи и специални ръкавици с по два палеца. Плетените изделия били безценни за местното население, но служели и за ключов износ и разменна стока срещу сол, захар, кафе и други. Когато мъжете тръгвали за риба, жените им оставали у дома да предат и плетат, както и да поправят вече поизносените дрехи.

Типично е, че колкото повече разноцветни нишки се вплитат, толкова по-топъл и с по-добра водоустойчивост е пуловерът, затова и измислянето на все по-сложни шарки винаги е било любимо занимание.

На север: Острови от вълна сред вълните на Атлантика (първа част)
Плетене на фарьорски пуловер с исландска вълна © Светла Стоянова

Широко разпространени били и ръкавиците с два палеца, така че, щом едната страна се поизноси от тегленето на рибарските мрежи, да могат да я обърнат с опакото и ръкавицата да има втори живот. В книжарниците днес се продават каталози, събрали всички открити фарьорски плетки и шарки, които продължават да вдъхновяват млади и стари плетачи и днес.

За съжаление обаче, в наши дни вълната, която се продава там, не е от фарьорски овце, а най-често от шетландски, новозеландски, исландски, перуански и други. Или дори и да се намира такава, тя често е смесица с вече споменатите – в неизвестно съотношение. След разговори с не един местен овчар научих, че ежегодно хилядите килограми остригана вълна, която притежава страхотни качества, бива изхвърляна или чисто и просто изгаряна. Обяснението – нямало пари във вълната.

На север: Острови от вълна сред вълните на Атлантика (първа част)
Фарьорски овце и отвесни скали © Светла Стоянова

Но как „фарьорското злато” се превръща в пепел?

Нямало машини, които да я предат, нямало и хора, които да се занимават с това… Разказаха ми, че някои ентусиасти се опитват да я изпращат във Великобритания или Германия, за да се изпреде от нея прежда и после да я върнат за продан в родината, но разбира се, тази разходка оскъпява крайния продукт до такава степен, че тези, които могат да си го позволят, са твърде малко.

Овцете на Фарьорските острови живеят почти като диви животни, защото са целогодишно навън на самотек. Те впечатляват с умението да се справят в екстремни условия, само и само да достигнат най-свежата зелена тревичка – катерят се по главозамайващи урви, спускат се в стръмни каньони, промъкват се из немислими скривалища. Един овчар ми разказа, че ги събират три пъти годишно: през зимата, за да им дадат лекарства и допълнително сено, през лятото, за да ги острижат, и през есента, за да изберат кои ще оставят, заколят или подберат за разплод.

Стадата всъщност са колективни и овцете се разпределят според това кой колко земя притежава. Това означава, че почти всеки фарьорец има определен дял овце. Все още до къщите съществуват hjallur – малки дървени колибки за сушене на месо и риба, които са силно проветриви, така че морският вятър да изсуши и по естествен път да осоли месото и рибата. Всеки разполага със свои запаси месо и такова почти никога не може да се намери в супермаркетите. За сметка на това в магазините е пълно с агнешко от Нова Зеландия или Исландия, което е шокиращо предвид броя на местните овце. Същото важи и за сушената риба, най-често внос отново от Исландия, при все че и за Фарьорските острови тя е основен поминък. Всичко това ме кара да се надявам, че традициите все още са живи и хората сами осигуряват храната си, съответно няма нужда да я купуват.

Един ден в селцето Gásadalur, попаднахме на бележка от местен, който продаваше типичното skerpikjøt – сушено и естествено осолено агнешко, престояло окачено във въпросните hjallur поне шест месеца. Похлопах на зелената дървена порта на типичната фарьорска къща и ми отвори брадат фарьорец, който ни заведе до своя сушилник за месо. Там избрахме един агнешки бут и той обясни, че е най-вкусно на тънки резени върху филия с масълце. Послушахме съвета му и след малко вече режехме неуверено от сушения бут. Вкусът беше наситен, подобно на някое плесенясало сирене, и едновременно с това пристрастяващ.

На север: Острови от вълна сред вълните на Атлантика (първа част)
Типична фарьорска къща © Светла Стоянова

Други страстни любители на особено добрия вкус обаче стигат до крайности и тук ще ви разкажа за две срещи с тях.

Тръгнахме по необозначен планински път, който се изкачваше постепенно до скалист ръб и оттатък ръба следваше стръмно нанадолнище. Заслизахме внимателно, а гледката насреща комбинираше островърхи планини, водопади, изливащи се право в морето, и скромен залив с тучна поляна, точно като за нашата палатка. Всичко това беше постоянно загръщано от валма облаци и препускащи мъгли. Бяхме изминали сигурно половината път надолу, когато съзряхме трима катерещи баира. Предупредиха ни, че нататък пътят е изключително труден и измамен, затова разумно обърнахме посоката и изкачихме на бърз ход стръмнината, по която току-що се бяхме спуснали. Оказа се, че тримата фарьорци се прибирали по този път, след като оставили два бивола в долината с тучната поляна, която си бяхме набелязали и ние. „От онази трева долу става най-вкусното месо!“, намигна с лукава усмивка единият от тях. Цял ден вървели с биволите, оставили ги и сега със сетни сили катереха последните скали по урвата. Явно си заслужаваше усилията! Щом стигнахме отново ръба, ни показаха друг, по-обиколен път до жадуваната от нас и биволите поляна. Чифтокопитни не срещнахме, но попаднахме на тайна ловна хижа, която приютявала ловците на диви зайци години наред. Вътре имаше тетрадка, в която местните бяха описвали перипетиите си около лова, а аз бях приятно учудена, че разбирам повечето от написаното, тъй като фарьорският език изключително се доближава до исландския. Оказа се, че зайците били внесени на островите от Норвегия през ХIX век като допълнителен източник на храна. Внесените диви зайци, които в норвежките планини зиме сменяли козината си с чистобяла, изменили зимната си премяна в синкавосива с бяла опашка, за да се вписват по-добре в не толкова снежните зими на островите.

На север: Острови от вълна сред вълните на Атлантика (първа част)
Стръмното спускане до поляната с биволите © Светла Стоянова

При среща с друг местен овчар научихме, че синовете му всяка година закарвали овцете с лодка до най-отдалечената и стръмна част на един от островите. Мястото било обрасло с ароматна ангелика, наричана у нас пищялка, която овцете обожавали, и после специфичното ѝ ухание оставало във вкуса на агнешкото. Затова двамата сина качвали напролет 40-килограмовите овце на въпросното място и ги прибирали наесен вече 80-килограмови, като цялото пренасяне на своенравните овце от и на лодката било доста рисковано. Всеки път, продължи овчарят, жена му умирала от страх за двамата си сина, тъй като неведнъж в неспокойните води по тези места имало лодко- и корабокрушения.

Освен на овцете, стопанството на страната разчита и на рибата. Географското положение предразполага към прекрасен улов, а фарьорците са умели рибари от векове. Преобладават атлантическата треска, скумрията и херингата, както и морският дявол, атлантическата камбала и др. Рибата е основна част от менюто на фарьорците и все още има хора, които я ловят малко преди вечеря.

Днес на много места в по-тихите заливи има и развъдници за сьомга. Още жива тя се пренася във фабрики, където се разфасова и изпраща по света. В тези развъдници обаче лесно се развиват болести и паразити сред рибите, а също така се използват вредни химикали, които вкупом замърсяват водите извън развъдниците и вредят на цялостната морска екосистема.

През последните години все повече се развива събирането на водорасли и производството на продукти от тях. Водораслите поглъщат енергия от слънцето и се хранят с въглероден диоксид, така че едновременно служат за пречиствателни станции на океана и имат безброй приложения – като заместител на месото, хранителни добавки, фураж за животни, за направа на опаковки от биопластмаса и дори за биогориво. Има бъдеще във водораслите и днес се откриват все повече полезни приложения в медицината, козметиката и хранителната индустрия, стига да се подходи с известна доза изобретателност.

Подложени на северния променлив климат, обсипани с овце и обкръжавани от риба и водорасли, Фарьорските острови придобиват все по-голяма популярност и като туристическа дестинация. Двата начина да стигнете до тях са с кораб или с полет до единственото летище, което е еднопистово. На място страната разполага с прекрасни пътища, впечатляващо количество междуостровни тунели, модерни фериботи и дори хеликоптери за обществен транспорт. Но повече за това – в следващата част, защото пътуването между островите и срещите с местните продължават…

Дъждът се сипе като през сито и ситни по разрошените от вятъра коси. Вървим през ниските растения и току разменяме погледи с овцете, които любопитно надигат глави от опосканата трева. Възрастните ни поздравяват с по едно „беее“, а сгушилите се до тях агънца гледат с големи очи като нарисувани в детска книжка. Щом подминаваме, започват да сучат от майките си и енергично да махат с опашка.

(Следва продължение.)

[$] Eliminating indirect calls for security modules

Post Syndicated from corbet original https://lwn.net/Articles/979683/

Like many kernel subsystems, the Linux security module (LSM) subsystem
makes extensive use of indirect function calls. Those calls, however, are
increasingly problematic, and the pressure to remove them has been growing.
The good news is that there is a patch
series
from KP Singh that accomplishes that goal. Its progress into
the mainline has been slow — this change was first proposed
by Brendan Jackman and Paul Renauld in 2020 — and this work has been caught
up in some wider controversies along the way, but it should be close to
being ready.

Takeaways From The Take Command Summit: Navigating Modern SOC Challenges

Post Syndicated from Emma Burdett original https://blog.rapid7.com/2024/07/02/takeaways-from-the-take-command-summit-navigating-modern-soc-challenges/

Takeaways From The Take Command Summit: Navigating Modern SOC Challenges

At our recent Take Command summit, experts delved into the pressing challenges faced by SOC teams. With 2,365 more data breaches in 2023 than in 2022 (74% of which were a direct result of cyber attacks), the need for robust security operations has never been greater.

Key takeaways from the 25 minute panel:

  1. Emphasizing Proactive Defense: SOC teams must prioritize proactive threat detection and intelligence gathering to stay ahead of evolving cyber threats.
  2. Enhancing Response Times: Reducing incident response times is crucial for mitigating the impact of security breaches and minimizing damage.
  3. Leveraging Advanced Tools: Utilizing advanced threat detection technologies, such as AI and machine learning, can significantly improve the ability to identify and respond to sophisticated attacks.

Key Quote:

“The increasing use of native tools by threat actors means they can stay hidden longer, complicating our detection efforts.”  – Lonnie Best, Detection & Response Services Manager, Rapid7.

The evolving threat landscape requires SOC teams to enhance detection capabilities and streamline operations. To dive deeper into these insights, click through to watch the full discussion.

Security updates for Tuesday

Post Syndicated from corbet original https://lwn.net/Articles/980393/

Security updates have been issued by AlmaLinux (httpd:2.4/httpd), Arch Linux (openssh), Fedora (cups, emacs, and python-urllib3), Gentoo (OpenSSH), Mageia (ffmpeg, gdb, openssl, python-idna, and python-imageio), Red Hat (golang and kernel), SUSE (booth, libreoffice, openssl-1_1-livepatches, podman, python-arcomplete, python-Fabric, python-PyGithub, python- antlr4-python3-runtime, python-avro, python-chardet, python-distro, python- docker, python-fakeredis, python-fixedint, pyth, python-Js2Py, python310, python39, and squid), and Ubuntu (cups and netplan.io).

The collective thoughts of the interwebz