Post Syndicated from Home Assistant original https://www.youtube.com/watch?v=ajd7IHGMFiI
Disaster recovery strategies for Amazon MWAA – Part 2
Post Syndicated from Chandan Rupakheti original https://aws.amazon.com/blogs/big-data/disaster-recovery-strategies-for-amazon-mwaa-part-2/
Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is a fully managed orchestration service that makes it straightforward to run data processing workflows at scale. Amazon MWAA takes care of operating and scaling Apache Airflow so you can focus on developing workflows. However, although Amazon MWAA provides high availability within an AWS Region through features like Multi-AZ deployment of Airflow components, recovering from a Regional outage requires a multi-Region deployment.
In Part 1 of this series, we highlighted challenges for Amazon MWAA disaster recovery and discussed best practices to improve resiliency. In particular, we discussed two key strategies: backup and restore and warm standby. In this post, we dive deep into the implementation for both strategies and provide a deployable solution to realize the architectures in your own AWS account.
The solution for this post is hosted on GitHub. The README in the repository offers tutorials as well as further workflow details for both backup and restore and warm standby strategies.
Backup and restore architecture
The backup and restore strategy involves periodically backing up Amazon MWAA metadata to Amazon Simple Storage Service (Amazon S3) buckets in the primary Region. The backups are replicated to an S3 bucket in the secondary Region. In case of a failure in the primary Region, a new Amazon MWAA environment is created in the secondary Region and hydrated with the backed-up metadata to restore the workflows.
The project uses the AWS Cloud Development Kit (AWS CDK) and is set up like a standard Python project. Refer to the detailed deployment steps in the README file to deploy it in your own accounts.
The following diagram shows the architecture of the backup and restore strategy and its key components:
- Primary Amazon MWAA environment – The environment in the primary Region hosts the workflows
- Metadata backup bucket – The bucket in the primary Region stores periodic backups of Airflow metadata tables
- Replicated backup bucket – The bucket in the secondary Region syncs metadata backups through Amazon S3 cross-Region replication
- Secondary Amazon MWAA environment – This environment is created on-demand during recovery in the secondary Region
- Backup workflow – This workflow periodically backups up Airflow metadata to the S3 buckets in the primary Region
- Recovery workflow – This workflow monitors the primary Amazon MWAA environment and initiates failover when needed in the secondary Region

Figure 1: The backup restore architecture
There are essentially two workflows that work in conjunction to achieve the backup and restore functionality in this architecture. Let’s explore both workflows in detail and the steps as outlined in Figure 1.
Backup workflow
The backup workflow is responsible for periodically taking a backup of your Airflow metadata tables and storing them in the backup S3 bucket. The steps are as follows:
- [1.a] You can deploy the provided solution from your continuous integration and delivery (CI/CD) pipeline. The pipeline includes a DAG deployed to the DAGs S3 bucket, which performs backup of your Airflow metadata. This is the bucket where you host all of your DAGs for your environment.
- [1.b] The solution enables cross-Region replication of the DAGs bucket. Any new changes to the primary Region bucket, including DAG files, plugins, and
requirements.txtfiles, are replicated to the secondary Region DAGs bucket. However, for existing objects, a one-time replication needs to be performed using S3 Batch Replication. - [1.c] The DAG deployed to take metadata backup runs periodically. The metadata backup doesn’t include some of the auto-generated tables and the list of tables to be backed up is configurable. By default, the solution backs up variable, connection, slot pool, log, job, DAG run, trigger, task instance, and task fail tables. The backup interval is also configurable and should be based on the Recovery Point Objective (RPO), which is the data loss time during a failure that can be sustained by your business.
- [1.d] Similar to the DAGs bucket, the backup bucket is also synced using cross-Region replication, through which the metadata backup becomes available in the secondary Region.
Recovery workflow
The recovery workflow runs periodically in the secondary Region monitoring the primary Amazon MWAA environment. It has two functions:
- Store the environment configuration of the primary Amazon MWAA environment in the secondary backup bucket, which is used to recreate an identical Amazon MWAA environment in the secondary Region during failure
- Perform the failover when a failure is detected
The following are the steps for when the primary Amazon MWAA environment is healthy (see Figure 1):
- [2.a] The Amazon EventBridge scheduler starts the AWS Step Functions workflow on a provided schedule.
- [2.b] The workflow, using AWS Lambda, checks Amazon CloudWatch in the primary Region for the SchedulerHeartbeat metrics of the primary Amazon MWAA environment. The environment in the primary Region sends heartbeats to CloudWatch every 5 seconds by default. However, to not invoke a recovery workflow spuriously, we use a default aggregation period of 5 minutes to check the heartbeat metrics. Therefore, it can take up to 5 minutes to detect a primary environment failure.
- [2.c] Assuming that the heartbeat was detected in 2.b, the workflow makes the cross-Region GetEnvironment call to the primary Amazon MWAA environment.
- [2.d] The response from the
GetEnvironmentcall is stored in the secondary backup S3 bucket to be used in case of a failure in the subsequent iterations of the workflow. This makes sure the latest configuration of your primary environment is used to recreate a new environment in the secondary Region. The workflow completes successfully after storing the configuration.
The following are the steps for the case when the primary environment is unhealthy (see Figure 1):
- [2.a] The EventBridge scheduler starts the Step Functions workflow on a provided schedule.
- [2.b] The workflow, using Lambda, checks CloudWatch in the primary Region for the scheduler heartbeat metrics and detects failure. The scheduler heartbeat check using the CloudWatch API is the recommended approach to detect failure. However, you can implement a custom strategy for failure detection in the Lambda function such as deploying a DAG to periodically send custom metrics to CloudWatch or other data stores as heartbeats and using the function to check that metrics. With the current CloudWatch-based strategy, the unavailability of the CloudWatch API may spuriously invoke the recovery flow.
- [2.c] Skipped
- [2.d] The workflow reads the previously stored environment details from the backup S3 bucket.
- [2.e] The environment details read from the previous step is used to recreate an identical environment in the secondary Region using the CreateEnvironment API call. The API also needs other secondary Region specific configurations such as VPC, subnets, and security groups that are read from the user-supplied configuration file or environment variables during the solution deployment. The workflow in a polling loop waits until the environment becomes available and invokes the DAG to restore metadata from the backup S3 bucket. This DAG is deployed to the DAGs S3 bucket as a part of the solution deployment.
- [2.f] The DAG for restoring metadata completes hydrating the newly created environment and notifies the Step Functions workflow of completion using the task token integration. The new environment now starts running the active workflows and the recovery completes successfully.
Considerations
Consider the following when using the backup and restore method:
- Recovery Time Objective – From failure detection to workflows running in the secondary Region, failover can take over 30 minutes. This includes new environment creation, Airflow startup, and metadata restore.
- Cost – This strategy avoids the overhead of running a passive environment in the secondary Region. Costs are limited to periodic backup storage, cross-Region data transfer charges, and minimal compute for the recovery workflow.
- Data loss – The RPO depends on the backup frequency. There is a design trade-off to consider here. Although shorter intervals between backups can minimize potential data loss, too frequent backups can adversely affect the performance of the metadata database and consequently the primary Airflow environment. Also, the solution can’t recover an actively running workflow midway. All active workflows are started fresh in the secondary Region based on the provided schedule.
- Ongoing management – The Amazon MWAA environment and dependencies are automatically kept in sync across Regions in this architecture. As specified in the Step 1.b of the backup workflow, the DAGs S3 bucket will need a one-time deployment of the existing resources for the solution to work.
Warm standby architecture
The warm standby strategy involves deploying identical Amazon MWAA environments in two Regions. Periodic metadata backups from the primary Region are used to rehydrate the standby environment in case of failover.
The project uses the AWS CDK and is set up like a standard Python project. Refer to the detailed deployment steps in the README file to deploy it in your own accounts.
The following diagram shows the architecture of the warm standby strategy and its key components:
- Primary Amazon MWAA environment – The environment in the primary Region hosts the workflows during normal operation
- Secondary Amazon MWAA environment – The environment in the secondary Region acts as a warm standby ready to take over at any time
- Metadata backup bucket – The bucket in the primary Region stores periodic backups of Airflow metadata tables
- Replicated backup bucket – The bucket in the secondary Region syncs metadata backups through S3 Cross-Region Replication.
- Backup workflow – This workflow periodically backups up Airflow metadata to the S3 buckets in both Regions
- Recovery workflow – This workflow monitors the primary environment and initiates failover to the secondary environment when needed

Figure 2: The warm standby architecture
Similar to the backup and restore strategy, the backup workflow (Steps 1a–1d) periodically backups up critical Amazon MWAA metadata to S3 buckets in the primary Region, which is synced in the secondary Region.
The recovery workflow runs periodically in the secondary Region monitoring the primary environment. On failure detection, it initiates the failover procedure. The steps are as follows (see Figure 2):
- [2.a] The EventBridge scheduler starts the Step Functions workflow on a provided schedule.
- [2.b] The workflow checks CloudWatch in the primary Region for the scheduler heartbeat metrics and detects failure. If the primary environment is healthy, the workflow completes without further actions.
- [2.c] The workflow invokes the DAG to restore metadata from the backup S3 bucket.
- [2.d] The DAG for restoring metadata completes hydrating the passive environment and notifies the Step Functions workflow of completion using the task token integration. The passive environment starts running the active workflows on the provided schedules.
Because the secondary environment is already warmed up, the failover is faster with recovery times in minutes.
Considerations
Consider the following when using the warm standby method:
- Recovery Time Objective – With a warm standby ready, the RTO can be as low as 5 minutes. This includes just the metadata restore and reenabling DAGs in the secondary Region.
- Cost – This strategy has an added cost of running similar environments in two Regions at all times. With auto scaling for workers, the warm instance can maintain a minimal footprint; however, the web server and scheduler components of Amazon MWAA will remain active in the secondary environment at all times. The trade-off is significantly lower RTO.
- Data loss – Similar to the backup and restore model, the RPO depends on the backup frequency. Faster backup cycles minimize potential data loss but can adversely affect performance of the metadata database and consequently the primary Airflow environment.
- Ongoing management – This approach comes with some management overhead. Unlike the backup and restore strategy, any changes to the primary environment configurations need to be manually reapplied to the secondary environment to keep the two environments in sync. Automated synchronization of the secondary environment configurations is a future work.
Shared considerations
Although the backup and restore and warm standby strategies differ in their implementation, they share some common considerations:
- Periodically test failover to validate recovery procedures, RTO, and RPO.
- Enable Amazon MWAA environment logging to help debug issues during failover.
- Use the AWS CDK or AWS CloudFormation to manage the infrastructure definition. For more details, see the following GitHub repo or Quick start tutorial for Amazon Managed Workflows for Apache Airflow, respectively.
- Automate deployments of environment configurations and disaster recovery workflows through CI/CD pipelines.
- Monitor key CloudWatch metrics like
SchedulerHeartbeatto detect primary environment failures.
Conclusion
In this series, we discussed how backup and restore and warm standby strategies offer configurable data protection based on your RTO, RPO, and cost requirements. Both use periodic metadata replication and restoration to minimize the area of effect of Regional outages.
Which strategy resonates more with your use case? Feel free to try out our solution and share any feedback or questions in the comments section!
About the Authors
 Chandan Rupakheti is a Senior Solutions Architect at AWS. His main focus at AWS lies in the intersection of Analytics, Serverless, and AdTech services. He is a passionate technical leader, researcher, and mentor with a knack for building innovative solutions in the cloud. Outside of his professional life, he loves spending time with his family and friends besides listening and playing music.
 Parnab Basak is a Senior Solutions Architect and a Serverless Specialist at AWS. He specializes in creating new solutions that are cloud native using modern software development practices like serverless, DevOps, and analytics. Parnab works closely in the analytics and integration services space helping customers adopt AWS services for their workflow orchestration needs.
[$] Nested bottom-half locking for realtime kernels
Post Syndicated from corbet original https://lwn.net/Articles/978189/
Software-interrupt handlers (also called “bottom halves”) have a long
history in the Linux kernel; for much of that history, developers have
wished that they could go away. One of their unfortunate characteristics
is that they can add unexpected latency to the execution of unrelated
processes; this problem is felt especially acutely in the
realtime-preemption community. The solution adopted there has created
problems of its own, though; in response Sebastian Andrzej Siewior is proposing
a new locking mechanism for realtime builds of the kernel that may have
benefits for non-realtime users as well.
Security updates for Monday
Post Syndicated from jake original https://lwn.net/Articles/978709/
Security updates have been issued by AlmaLinux (389-ds-base, buildah, c-ares, cockpit, containernetworking-plugins, fence-agents, gdk-pixbuf2, gvisor-tap-vsock, libreoffice, podman, python-idna, rpm-ostree, and ruby), Debian (atril, chromium, ffmpeg, libndp, libvpx, nano, plasma-workspace, pymongo, roundcube, sendmail, and thunderbird), Fedora (booth and thunderbird), Mageia (aom, atril, libvpx, nano, nss, firefox, and vte), Red Hat (linux-firmware), SUSE (bind, booth, mariadb, openssl-1_1, php7, php8, and webkit2gtk3), and Ubuntu (linux-azure, linux-azure-fde, linux-azure, linux-gke, and linux-nvidia-6.5).
Three ways Amazon Q Developer agent for code transformation accelerates Java upgrades
Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/three-ways-amazon-q-developer-agent-for-code-transformation-accelerates-java-upgrades/
When Amazon Web Services (AWS) launched Amazon Q Developer agent for code transformation as a preview last year to upgrade Java applications, we saw many organizations desire to significantly accelerate their Java upgrades. Previously, these upgrades were considered daunting, a time-consuming manual task requiring weeks if not months of effort and with Amazon Q Developer they could significantly reduce that burden. Companies such as Toyota, Novacamp, Pragma and Persistent saw productivity gains not only in reducing the amount of time the upgrades would take, but re-prioritizing that time saved into other business priorities related to the software development lifecycle (SDLC). In addition, a small team of AWS developers upgraded over 1000 carefully chosen applications from multiple independent services. These applications used less than 10 dependencies and required minimal mandatory changes to the application code for the upgrade. While we saw a high degree of upgrade success for simpler applications, we also heard from customers who wanted even more capabilities in the Amazon Q Developer agent for code transformation. They expected the agent to upgrade their libraries to the latest major versions, replace deprecated API calls, and provide more explainability of changes made.
We added these and more capabilities to the agent at General Availability (GA). Today, we’re going into detail on the following four categories for what Amazon Q Developer can do for your Java upgrades: major version upgrades of popular frameworks, directly replacing deprecated API calls on your behalf, clear explainability on code changes, and using some examples of our unprecedented AI technology powered by Amazon Bedrock, that is capable, for example, of correcting more compilation errors that can be encountered when attempting the build in Java 17.
This blog post will dive deeper into these three ways we improved the product experience through an example application. You can download the application from this GitHub repository.
About the application
This is a Java 1.8 based microservice application which displays free list of movies for the month based on configuration stored in AWS AppConfig service using AWS SDK. This application was first open sourced in 2020 and uses legacy versions of libraries such as Spring Boot 2.x, Log4j 2.13.x, Mockito 1.x, Javax and Junit 4. You can download the sample project to try it for yourself.
(1) Popular framework upgrades
While Spring Boot version 2.7 is compatible with Java 17, Amazon Q Developer agent for code transformation can bring your applications up to version 3.2. This has been helpful because it can be time consuming to correct all the changes in annotations and code implementation that are no longer compatible when going into the new major version upgrade. Moreover, this version of Spring Boot provides improved observability, performance improvements, modernized security, and overall enhanced development experience. Let’s dive into some examples of where you see Amazon Q Developer accelerate some of this heavy lifting during the upgrade process.
When working with file uploads in Spring Boot v2, you would typically use the @RequestParam("file") annotation to bind the uploaded file to a method parameter. However, in Spring Boot v3.2, this approach has been updated to better align with the Jakarta EE specifications. Instead of using a plain String parameter, you’ll need to use the MultipartFile class from the org.springframework.web.multipart package. Here is an example before and after code transformation with Amazon Q Developer:
Java 8 code with Spring v2
@RequestMapping(value = "/movies/{movie}/edit", method = POST)
public String processUpdateMovie(@Valid Movie movie, BindingResult result,
                           @PathVariable("movieId") int movieId) {

   ...
}
Java 17 code upgraded by Amazon Q Developer with Spring v3
@PostMapping("/movies/{movie}/edit")
public String processUpdateMovie(@Valid Movie movie, BindingResult result,
                           @PathVariable int movieId) {

...
}
Associated dependency updates in pom.xml
<parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>2.0.5.RELEASE</version>
</parent>
to
<parent>
    <groupId>org.springframework.boot</groupId>
    <artifactId>spring-boot-starter-parent</artifactId>
    <version>3.2.5</version>
</parent>
The following lists some common libraries we’ve seen you all use, with the corresponding compatible version in Java 8 and what we’re capable of upgrading to using Q Developer. This list isn’t comprehensive of all libraries, the intent is to show some common ones. This could change in the future and is up-to-date as of the time of this publication.

Let’s review a few examples from the Sample project.
Java 8 code with Junit 4
import org.junit.Test;
import org.junit.runner.RunWith;
import org.springframework.boot.test.context.SpringBootTest;
import org.springframework.test.context.junit4.SpringRunner;
import com.amazonaws.samples.appconfig.movies.MoviesController;

@RunWith(SpringRunner.class)
@SpringBootTest
public class MovieTest {
  ...
}
@Before
public void setUp() {
MockitoAnnotations.initMocks(this);
moviesController = new MoviesController();
moviesController.env = env;
}<dependency>
<groupId>junit</groupId>
<artifactId>junit</artifactId>
<version>4.13.1</version>
<scope>test</scope>
</dependency>Java 17 code upgraded by Amazon Q Developer with Junit 5:
import org.junit.jupiter.api.Test;
import org.springframework.boot.test.context.SpringBootTest;
import com.amazonaws.samples.appconfig.movies.MoviesController;

@SpringBootTest
public class MovieTest {
  ...
}
@BeforeEach
public void setUp() {
MockitoAnnotations.initMocks(this);
moviesController = new MoviesController();
moviesController.env = env;
}<dependency>
<groupId>org.junit.jupiter</groupId>
<artifactId>junit-jupiter</artifactId>
<scope>test</scope>
</dependency>(2) Deprecated APIs
One of the biggest challenges organizations face when upgrading to a newer version of Java is dealing with deprecated APIs. As new language features and libraries are introduced, older APIs are often marked as deprecated and eventually removed in subsequent releases. This can lead to compilation errors and compatibility issues, requiring developers to manually identify and replace these deprecated APIs throughout their codebase – a time-consuming and error-prone process.
In our sample application, you will see a variety of deprecated APIs that are addressed by Q Developer as an output of the transformation to Java 17. Here are some examples:
Before:
bd.divide(bd2, BigDecimal.ROUND_DOWN);
bd.divide(bd2, 1, BigDecimal.ROUND_CEILING);
After:
bd.divide(bd2, RoundingMode.DOWN);
bd.divide(bd2, 1, RoundingMode.CEILING);
Before:
String enc1 = new sun.misc.BASE64Encoder().encode(bytes);After:
import java.util.Base64;
String enc1 = Base64.getEncoder().encodeToString(bytes);
Before:
import javax.security.cert.*;After:
import java.security.cert.*;Before:
import static org.mockito.Matchers.anyInt;
...
when(mocklist.get(anyInt())).thenReturn("Movies");
After:
import static org.mockito.ArgumentMatchers.anyInt;
...
when(mocklist.get(anyInt())).thenReturn("Movies");
Java versions before 15 required explicit line terminators, string concatenations, and delimiters to embed multi-line code snippets. Java 15 introduced text blocks to simplify embedding code snippets and text sequences, particularly useful for literals like HTML, JSON, and SQL. Text blocks are an alternative string representation that can replace traditional double-quoted string literals, allowing multi-line strings without explicit line terminators or concatenations. Amazon Q Developer agent for code transformation will migrate your complex multi-line text which not so readable to text blocks.
Before:
private static String getMovieItemsHtml(Movie[] movies) {
        StringBuilder movieItemsHtml = new StringBuilder();
        for (Movie movie : movies) {
            movieItemsHtml.append("<div class='movie-item'>"
                    + "<p>ID: ").append(movie.getId()).append("</p>"
                    + "<h3>").append(movie.getMovieName()).append("</h3>"
                    + "<hr width=\"100%\" size=\"2\" color=\"blue\" noshade>"
                    + "</div>");
        }
        return movieItemsHtml.toString();
    }
After:
private static String getMovieItemsHtml(Movie[] movies) {
        StringBuilder movieItemsHtml = new StringBuilder();
        for (Movie movie : movies) {
            movieItemsHtml.append("""
                    <div class='movie-item'>\
                    <p>ID: \
                    """).append(movie.getId()).append("""
                    </p>\
                    <h3>\
                    """).append(movie.getMovieName()).append("""
                    </h3>\
                    <hr width="100%" size="2" color="blue" noshade>\
                    </div>\
                    """);
        }
        return movieItemsHtml.toString();
    }
Including these examples above in the sample app, Q Developer supports a wide range of abilities to address deprecated APIs across various domains, including primitive type constructors and conversions, character and string utilities, date and time handling, mathematical operations, networking and sockets, security and cryptography, concurrent programming and atomics, reflection and bytecode generation, as well as a significant number of deprecated methods related to Swing and AWT components. Whether it’s replacing outdated methods for handling dates, encoding URLs, or working with BigDecimal arithmetic, we can automatically update your code to use their modern equivalents. It also addresses deprecations in areas like multicast sockets, atomic variables, and even bytecode generation using ASM.
With the Q Developer agent for code transformation, we’ve made it easier than ever to handle deprecated APIs during your Java 17 migration. Q Developer is capable of automatically detecting and replacing deprecated API calls with their modern equivalents, saving you countless hours of manual effort and reducing the risk of introducing bugs or regressions.
(3) Unprecedented AI technology
Even after addressing deprecated APIs and framework upgrades, the process of migrating to a new Java version can still encounter compilation errors or unexpected behavior. These issues can arise from subtle changes in language semantics, incompatibilities between libraries, or other factors that are difficult to anticipate and diagnose.
To tackle this challenge, the Q Developer agent for code transformation leverages our self-debugging technology powered by Bedrock which analyzes the context of compilation errors and is capable of implementing targeted code modifications to resolve them. Here are some examples.
Java 1.8 with javax.security.X509Certificate:
import javax.security.cert.*;
import java.io.File;
import java.io.FileInputStream;
import java.io.FileNotFoundException;
import java.io.InputStream;
import java.util.Date;

public class Security {
    public Certificate getCertificate(File certFile) throws CertificateExpiredException, CertificateNotYetValidException {
        X509Certificate cert = null;
        try {
            InputStream inStream = new FileInputStream(certFile);
            cert = X509Certificate.getInstance(inStream);
        } catch (CertificateException e) {
            throw new RuntimeException(e);
        } catch (FileNotFoundException e) {
            throw new RuntimeException(e);
        }
        cert.checkValidity(new Date());
        return cert;
    }

}
Amazon Q changing dependency from javax.security to java.security package and fixing compilation errors related to X509Certificate . It modified the code to get the X509Certificate from CertificateFactory instead of directly getting from the X509Certificate.getInstance.
import java.security.cert.*;
import java.io.File;
import java.io.FileInputStream;
import java.io.FileNotFoundException;
import java.io.InputStream;
import java.util.Date;

public class Security {
    public Certificate getCertificate(File certFile) throws CertificateExpiredException, CertificateNotYetValidException {
        X509Certificate cert = null;
        try {
            InputStream inStream = new FileInputStream(certFile);
            CertificateFactory cf = CertificateFactory.getInstance("X.509");
            cert = (X509Certificate) cf.generateCertificate(inStream);
        } catch (CertificateException e) {
            throw new RuntimeException(e);
        } catch (FileNotFoundException e) {
            throw new RuntimeException(e);
        }
        cert.checkValidity(new Date());
        return cert;
    }

}
With Q Developer’s AI technology, it can automatically correct a wider range of issues that would otherwise require manual intervention, further streamlining the upgrade process and reducing the risk of costly delays or regressions.

Conclusion
Throughout this blog post, we explored the three major areas of improvement in the Amazon Q Developer agent for code transformation since its general availability: major version upgrades of popular frameworks, direct replacement of deprecated library calls, and leveraging our AI technology using Amazon Bedrock capabilities to correct compilation errors during Java 17 migration. By addressing these critical aspects, the Q Developer agent has become an even more powerful tool for organizations seeking to unlock the benefits of Java 17 while minimizing the time and effort required for application upgrades. As we continue to enhance the Q Developer agent based on customer feedback, we encourage you to explore the open source example application provided and experience firsthand how this tool can streamline your Java modernization journey. See Getting Started with Amazon Q Developer agent for code transformation for a step by step process to transforming a java application with Q Developer.
About the authors
 Jonathan Vogel
Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.
 Venugopalan Vasudevan
Venugopalan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation.
Today in History: June 17
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=x-rn9renzsU
Nikon Z6III: Improved Focus, Epic Video & New Sensor Tech
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=t2O0sbUdf8Q
Using LLMs to Exploit Vulnerabilities
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/06/using-llms-to-exploit-vulnerabilities.html
Interesting research: “Teams of LLM Agents can Exploit Zero-Day Vulnerabilities.”
Abstract: LLM agents have become increasingly sophisticated, especially in the realm of cybersecurity. Researchers have shown that LLM agents can exploit real-world vulnerabilities when given a description of the vulnerability and toy capture-the-flag problems. However, these agents still perform poorly on real-world vulnerabilities that are unknown to the agent ahead of time (zero-day vulnerabilities).
In this work, we show that teams of LLM agents can exploit real-world, zero-day vulnerabilities. Prior agents struggle with exploring many different vulnerabilities and long-range planning when used alone. To resolve this, we introduce HPTSA, a system of agents with a planning agent that can launch subagents. The planning agent explores the system and determines which subagents to call, resolving long-term planning issues when trying different vulnerabilities. We construct a benchmark of 15 real-world vulnerabilities and show that our team of agents improve over prior work by up to 4.5×.
The LLMs aren’t finding new vulnerabilities. They’re exploiting zero-days—which means they are not trained on them—in new ways. So think about this sort of thing combined with another AI that finds new vulnerabilities in code.
These kinds of developments are important to follow, as they are part of the puzzle of a fully autonomous AI cyberattack agent. I talk about this sort of thing more here.
S11 E15: Trump’s Second Term, MLK & Red Lobster Update: 6/16/24: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=QCRySbsLKiA
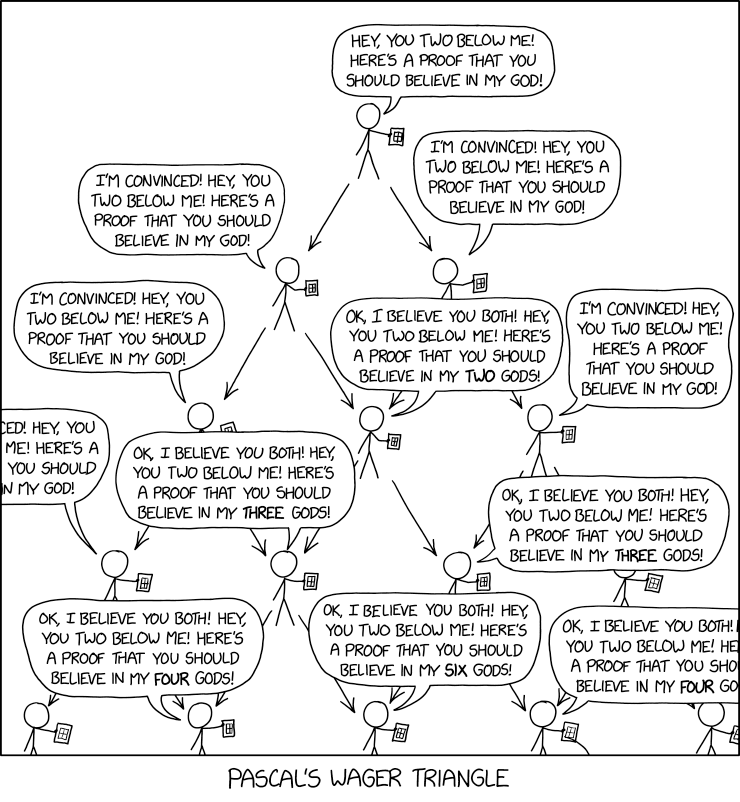
Pascal’s Wager Triangle
Post Syndicated from xkcd.com original https://xkcd.com/2947/
Kernel prepatch 6.10-rc4
Post Syndicated from corbet original https://lwn.net/Articles/978629/
Linus has released 6.10-rc4 for testing.
“Apart from a rather unusual spike in the diffstat due to a parisc fix,
“
things look normal and pretty small.
Some weekend stable kernel updates
TRENDnet TEG-3102WS 8-port 2.5GbE and 2-port 10G Managed Switch Review
Post Syndicated from Rohit Kumar original https://www.servethehome.com/trendnet-teg-3102ws-8-port-2-5gbe-and-2-port-10g-managed-switch-review/
The TRENDnet TEG-3102WS sports MaxLinear switch chips to offer an 8-port 2.5GbE and 2-port SFP+ web managed switch
The post TRENDnet TEG-3102WS 8-port 2.5GbE and 2-port 10G Managed Switch Review appeared first on ServeTheHome.
Broadway’s The Wiz | Talks at Google
Post Syndicated from Talks at Google original https://www.youtube.com/watch?v=6CljvurQ4-o
2024-06-16 празнуване на sysadminday
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3480
По традиция деня на системния администратор е последния петък на юли.
Дали за тази година има желаещи да го празнуваме в София? Нещо като Маймунарника, или някоя кръчма по центъра, някой би ли дошъл?:)
Comic for 2024.06.16 – Nerf
Post Syndicated from Explosm.net original https://explosm.net/comics/nerf
New Cyanide and Happiness Comic
Flying Boat Versus UC-66.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=R5M8csP69nw
Nipples 3:16
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/nipples3-16/


Reports from the Python Language Summit
Post Syndicated from corbet original https://lwn.net/Articles/978541/
The Python Software Foundation has published a
set of reports from the 2024 Python Language summit. Topics covered
include version numbering, the limited C API, a new default read-eval-print
loop, and Python’s security model in light of the XZ backdoor:
For multiple reasons like being able to fix bugs and
single-maintainer modules, CPython doesn’t require reviewers on the
pull requests of core developers. This can lead to “unilateral
action”, meaning that a change is introduced into CPython without
the review of someone besides the author. Other situations like
release managers backporting fixes to other branches without review
are common.
The Ring of Fire: Earth’s Hotspot for Volcanoes and Earthquakes
Post Syndicated from Geographics original https://www.youtube.com/watch?v=VLQsde6-xJk