When we launched Amazon Q Developer, our goal was to bring AI assistance directly into the developer workflow. Customers adopted Q Developer across VS Code, JetBrains, Eclipse, and Visual Studio, using it for code generation, debugging, and chat-based guidance. Q Developer proved that AI belongs in the inner loop of software development.
Over the past year, we’ve learned that the most impactful AI developer experiences go far beyond code generation and completion. Developers need AI that understands their entire project: the architecture, the requirements, the tests, and the intent behind the code. It requires a purpose-built environment. That’s why we built Kiro.
What is Kiro? Kiro is an agentic development environment (IDE, CLI) built from the ground up for spec-driven development. Instead of reacting to individual prompts, Kiro works from structured specifications to plan, implement, and verify changes across your entire codebase. Key capabilities include:
Specs — Define what you want to build in structured, natural-language requirements that Kiro uses to drive implementation end to end.
Hooks — Automated triggers that run on file save, commit, or other events to enforce standards, run tests, or update documentation without manual intervention.
Steering files — Project-level configuration that gives Kiro persistent context about your architecture, conventions, and constraints.
Custom subagents — Specialized AI agents you define for domain-specific tasks like security review, API contract validation, or infrastructure provisioning.
Powers — Composable capability modules that extend Kiro’s agentic behavior for your specific workflows.
Kiro also includes everything developers rely on in Q Developer today: agentic coding, inline chat, terminal integration, and MCP support.
What’s changing Amazon Q Developer IDE plugins and paid Subscriptions will reach end of support on April 30, 2027, giving customers 12 months to transition to Kiro.
New signups will no longer available starting May 15, 2026. New Q Developer Free Tier account creation (via Builder ID in IDE plugins) and new Q Developer subscription creation (via the AWS Console) will be blocked.
Model changes: starting May 29, 2026, Opus 4.6 will no longer be available on Q Developer Pro. Opus 4.5 and all other existing models remain available. The latest coding models, including Opus 4.7, are available exclusively on Kiro.
Existing customers retain access. If you access Q Developer via a Q Developer Pro subscription or Kiro subscription, you will continue to have access to the Q Developer IDE plugins until April 30, 2027. The May 15, 2026 change affects new signups for Q Developer accounts and subscriptions.
IDE plugin listings remain live. Q Developer plugins will remain published on all four IDE marketplaces with a deprecation notice directing users to Kiro. Critical bugfixes will continue to be pushed to existing users through the transition window.
What’s not changing Amazon Q Developer in the AWS Management Console and first-party AWS experiences (AWS Marketing Website, AWS Documentation Website, AWS Console Mobile App, and Amazon Q Developer for Chat Apps – Slack & Microsoft Teams) are not impacted by this sunset and will continue to be available to AWS customers. Customers using Q Developer in these products will retain access to their current subscription benefits and capabilities.
What you should do
Explore Kiro today. Download Kiro at kiro.dev and try spec-driven development on your next project.
Performance issues in analytics environments often remain invisible until they disrupt dashboards, delay ETL jobs, or impact business decisions. For teams running Amazon Redshift Serverless, unmonitored query queues, long-running queries, or unexpected spikes in compute capacity can degrade performance and increase costs if left undetected.
Amazon Redshift Serverless streamlines running analytics at scale by removing the need to provision or manage infrastructure. However, even in a serverless environment, maintaining visibility into performance and usage is essential for efficient operation and predictable costs. While Amazon Redshift Serverless provides advanced built-in dashboards for monitoring performance metrics, delivering notifications directly to platforms like Slack, brings another level of agility. Real-time alerts in the team’s workflow enable faster response times and more informed decision-making without requiring constant dashboard monitoring.
In this post, we show you how to build a serverless, low-cost monitoring solution for Amazon Redshift Serverless that proactively detects performance anomalies and sends actionable alerts directly to your selected Slack channels. This approach helps your analytics team identify and address issues early, often before your users notice a problem.
Solution overview
The solution presented in this post uses AWS services to collect key performance metrics from Amazon Redshift Serverless, evaluate them against thresholds that you can flexibly configure, and notify you when anomalies are detected.
The workflow operates as follows:
Scheduled execution – An Amazon EventBridge rule triggers an AWS Lambda function on a configurable schedule (by default, every 15 minutes during business hours).
Metric collection – The AWS Lambda function gathers metrics including queued queries, running queries, compute capacity (RPUs), data storage usage, table count, database connections, and slow-running queries using Amazon CloudWatch and the Amazon Redshift Data API.
Threshold evaluation – Collected metrics are compared against your predefined thresholds that reflect acceptable performance and usage limits.
Alerting – When a threshold is exceeded, the Lambda function publishes a notification to an Amazon SNS topic.
Observability – Lambda execution logs are stored in Amazon CloudWatch Logs for troubleshooting and auditing.
This architecture is fully serverless and requires no changes to your existing Amazon Redshift Serverless workloads. To simplify deployment, we provide an AWS CloudFormation template that provisions all required resources.
Prerequisites
Before deploying this solution, you must collect information about your existing Amazon Redshift Serverless workgroup and namespace that you want to monitor. To identify your Amazon Redshift Serverless resources:
Provide details for your existing Amazon Redshift Serverless environment. These values connect the monitoring solution to your Redshift environment. Some parameters come with the default values that you can replace with your actual configuration.
Parameter
Default value
Description
Amazon Redshift Workgroup Name
Your Amazon Redshift Serverless workgroup name.
Amazon Redshift Namespace Name
Your Amazon Redshift Serverless namespace name.
Amazon Redshift Workgroup ID
Workgroup ID (UUID) of the Amazon Redshift Serverless workgroup to monitor. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Namespace ID (UUID) of the Amazon Redshift Serverless namespace. Must follow the UUID format: xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx (lowercase hexadecimal with hyphens).
Database Name
dev
Target Amazon Redshift database for SQL-based diagnostic and monitoring queries.
Monitoring schedule
The default schedule runs diagnostic SQL queries every 15 minutes during business hours, balancing responsiveness and cost efficiency. Running more frequently might increase costs, while less frequent monitoring could delay detection of performance issues. You can adjust this schedule to your actual need.
Parameter
Default value
Description
Schedule Expression
cron(0/15 8-17 ? * MON-FRI *)
EventBridge schedule expression for Lambda function execution. Default runs every 15 minutes, Monday through Friday, 8 AM to 5 PM UTC.
Threshold configuration
Thresholds should be tuned based on your workload characteristics.
Parameter
Default value
Description
Queries Queued Threshold
20
Alerts threshold for queued queries.
Queries Running Threshold
20
Alerts threshold for running queries.
Compute Capacity Threshold (RPUs)
64
Alert threshold for compute capacity (RPUs).
Data Storage Threshold (MB)
5242880
Threshold for data storage in MB (default 5 TB).
Table Count Threshold (MB)
1000
Alerts threshold for total table count.
Database Connections Threshold
50
Alert threshold for database connections.
Slow Query Threshold (seconds)
10
Thresholds in seconds for slow query detection.
Query Timeout (Seconds)
30
Timeout for SQL diagnostics queries.
Tip: Start with conservative thresholds and refine them after observing baseline behavior for one to two weeks.
Lambda configuration
Configure the AWS Lambda function settings. The selected default values are appropriate for most monitoring scenarios. You may want to change them only in case of troubleshooting.
If your organization has network isolation requirements, you can optionally enable VPC deployment for the Lambda function. When enabled, the Lambda function runs within your specified VPC subnets, providing network isolation and allowing access to VPC-only resources.
Parameter
Default value
Description
VPC ID
VPC ID for Lambda deployment (required if EnableVPC is true). The Lambda function will be deployed in this VPC. Ensure that the VPC has appropriate routing (NAT Gateway or VPC Endpoints) to allow Lambda to access AWS services like CloudWatch, Amazon Redshift, and Amazon SNS.
VPC Subnet IDs
Comma-separated list of subnet IDs for Lambda deployment (required if EnableVPC is true).
Security Group IDs
Comma-separated list of security group IDs for Lambda (optional). If not provided and EnableVPC is true, a default security group will be created with outbound HTTPS access. Custom security groups must allow outbound HTTPS (port 443) to AWS service endpoints.
Note that VPC deployment might increase cold start times and requires an NAT Gateway or VPC endpoints for AWS service access. We recommend provisioning interface VPC endpoints (through AWS PrivateLink) for the five services the Lambda function calls which keeps all traffic private without the recurring cost of a NAT Gateway.
Security configuration – Encryption
If your organization requires encryption of data at rest, you can optionally enable AWS Key Management Service (AWS KMS) encryption for the Lambda function’s environment variables, CloudWatch Logs, and SNS topic. When enabled, the template encrypts each resource using the AWS KMS keys that you provide, either a single shared key for all three services, or individual keys for granular key management and audit separation.
Parameter
Default value
Description
Shared KMS Key ARN
AWS KMS key ARN to use for all encryption (Lambda, Logs, and SNS) unless service-specific keys are provided. This streamlines key management by using a single key for all services. The key policy must grant encrypt/decrypt permissions to Lambda, CloudWatch Logs, and SNS.
Lambda KMS Key ARN
AWS KMS key ARN for Lambda environment variable encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant decrypt permissions to the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
CloudWatch Logs KMS Key ARN
AWS KMS key ARN for CloudWatch Logs encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to the CloudWatch Logs service. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
SNS Topic KMS Key ARN
AWS KMS key ARN for SNS topic encryption (optional, overrides SharedKMSKeyArn). Use this for separate key management per service. The key policy must grant encrypt/decrypt permissions to SNS service and the Lambda execution role. If not provided, SharedKMSKeyArn will be used when EnableKMSEncryption is true.
Enable Dead Letter Queue
False
Optionally enable Dead Letter Queue (DLQ) for failed Lambda invocations to improve reliability and security monitoring. When enabled, events that fail after all retry attempts will be sent to an SQS queue for investigation and potential replay. This helps prevent data loss, provides visibility into failures, and enables security audit trails for monitoring anomalies. The DLQ retains messages for 14 days.
Note that AWS KMS encryption requires the key policy to grant appropriate permissions to each consuming service (Lambda, CloudWatch Logs, and SNS).
On the review page, select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
Choose Submit.
Resources created
The CloudFormation stack creates the following resources:
EventBridge rule for scheduled execution
AWS Lambda function (Python 3.12 runtime)
Amazon SNS topic for alerts
IAM role with permissions for CloudWatch, Amazon Redshift Data API, and SNS
CloudWatch Log Group for Lambda logs
Note: CloudFormation deployment typically takes 10–15 minutes to complete. You can monitor progress in real time under the Events tab of your CloudFormation stack.
Post-deployment configuration
After the CloudFormation stack has been successfully created, complete the following steps.
Note the values for LambdaRoleArn and SNSTopicArn. You will need these in subsequent steps.
Step 2: Grant Amazon Redshift permissions
Grant permissions to the Lambda function to query Amazon Redshift system tables for monitoring data. Complete the following steps to grant the necessary access:
In the left navigation pane, choose Query Editor V2.
Connect to your Amazon Redshift Serverless workgroup.
Execute the following SQL commands, replacing <IAM Role ARN> with the LambdaRoleArn value from your CloudFormation outputs:
CREATE USER "IAMR:<IAM Lambda Role>" WITH PASSWORD DISABLE;

GRANT ROLE "sys:monitor" TO "IAMR:<IAM Role>";
These commands create an AmazonRedshift user associated with the Lambda IAM role and grant it the sys:monitor Amazon Redshift role. This role provides read-only access to catalog and system tables without granting permissions to user data tables.
Step 3: Configure Slack notifications
Amazon Q Developer in chat applications provides native AWS integration and managed authentication, removing custom webhook code and reducing setup complexity. To receive alerts in Slack, configure Amazon Q Developer in Chat Applications to connect your SNS topic to your preferred Slack channel:
When configuring the Slack channel, ensure that you select the correct AWS Region where you deployed the CloudFormation stack.
In the Notifications section, select the SNS topic created by your CloudFormation stack (refer to the SNSTopicArn output value).
Keep the default IAM read-only permissions for the channel configuration.
After configured, alerts automatically appear in Slack whenever thresholds are exceeded.
Cost considerations
With the default configuration, this solution incurs minimal ongoing costs. The Lambda function executes approximately 693 times per month (every 15 minutes during an 8-hour business day, Monday through Friday), resulting in a monthly cost of approximately $0.33 USD. This includes Lambda compute costs ($0.26) and CloudWatch GetMetricData API calls ($0.07). All other services (EventBridge, SNS, CloudWatch Logs, and Amazon Redshift Data API). The Amazon Redshift Data API has no additional charges beyond the minimal Amazon Redshift Serverless RPU consumption for the Amazon Redshift Serverless system table query execution. You can reduce costs by decreasing the monitoring frequency (such as, every 30 minutes) or increase responsiveness by running more frequently (such as, every 5 minutes) with a proportional cost increase.
All costs are estimates and may vary based on your environment. Variations often occur because queries scanning system tables may take longer or require additional resources depending on the system complexity
Security best practices
This solution implements the following security controls:
IAM policies scoped to specific resource ARNs for the Amazon Redshift workgroup, namespace, SNS topic, and log group.
Data API statement access restricted to the Lambda function’s own IAM user ID.
Read-only sys:monitor database role for operational metadata access. Limit to the role created by the CloudFormation template.
Reserved concurrent executions capped at five.
To further strengthen your security posture, consider the following enhancements:
Enable EnableKMSEncryption to encrypt environment variables, logs, and SNS messages at rest.
Enable EnableVPC to deploy the function within a VPC for network isolation.
Audit access through AWS CloudTrail.
Important: This is sample code for non-production usage. Work with your security and legal teams to meet your organizational security, regulatory, and compliance requirements before deployment. This solution demonstrates monitoring capabilities but requires additional security hardening for production environments, including encryption configuration, IAM policy scoping, VPC deployment, and comprehensive testing.
Clean up
To remove all resources and avoid ongoing charges if you don’t want to use the solution anymore:
Remove the Slack integration from Amazon Q Developer in chat applications.
Troubleshooting
If no metrics or incomplete SQL diagnostics are returned, verify that the Amazon Redshift Serverless workgroup is active with recent query activity, and ensure the database user has the sys:monitor role (GRANT ROLE sys:monitor TO <user>) in the query editor. Without this role, queries execute successfully but only return data visible to that user’s permissions rather than the full cluster activity.
For VPC-deployed functions that fail to reach AWS services, confirm that VPC endpoints or a NAT Gateway are configured for CloudWatch, Amazon Redshift Data API, Amazon Redshift Serverless, SNS, and CloudWatch Logs.
If the Lambda function times out, increase the LambdaTimeout and QueryTimeoutSeconds parameters. The default timeout of 240 seconds accommodates most workloads, but clusters with many active queries may require additional time for SQL diagnostics to complete.
Conclusion
In this post, we showed how you can build a proactive monitoring solution for Amazon Redshift Serverless using AWS Lambda, Amazon CloudWatch, and Amazon SNS with Slack integration. By automatically collecting metrics, evaluating thresholds, and delivering alerts in near real time to Slack or your preferred collaborative platform, this solution helps detect performance and cost issues early. Because the solution itself is serverless, it aligns with the operational simplicity goals of Amazon Redshift Serverless—scaling automatically, requiring minimal maintenance, and delivering high value at low cost. You can extend this foundation with additional metrics, diagnostic logic, or alternative notification channels to meet your organization’s needs.
To learn more, see the Amazon Redshift documentation on monitoring and performance optimization.
The AI-Driven Development Life Cycle (AI-DLC) methodology marks a significant change in software development by strategically assigning routine tasks to AI while maintaining human oversight for critical decisions. Amazon Q Developer, a generative AI coding assistant, supports the entire software development lifecycle and offers the Project Rules feature, allowing users to tailor their development practices within the platform.
Recently, AWS made its AI-DLC workflow open-source, enabling developers to create software using this methodology. This workflow is implemented in Amazon Q Developer through its Project Rules customization feature. In this post, we will demonstrate how the AI-DLC workflow operates in Amazon Q Developer using an example use case.
AI-DLC Workflow Overview
The AI-DLC workflow is the practical implementation of the AI-DLC methodology for executing software development tasks. As outlined in the AI-DLC Method Definition Paper, the workflow has three phases. These phases are Inception, Construction, and Operations. Inception involves planning and architecture. Construction focuses on design and implementation. Operations cover deployment and monitoring. Each phase includes distinct stages. These stages address specific software development life cycle functions. The workflow adapts to project requirements. It analyzes requests, codebases, and complexity. This analysis determines the necessary stages. Simple bug fixes skip planning. They go directly to code generation. Complex features need requirements analysis. They also require architectural design and detailed testing.
The workflow maintains quality and control through structured milestones and transparent decision-making. At each phase, AI-DLC asks clarifying questions, creates execution plans, and waits for approval. Every decision, input, and response is logged in an audit trail for traceability. Whether building a new microservice, refactoring legacy code, or fixing a production bug, AI-DLC scales its rigor to match needs—comprehensive when complex, efficient when simple, and always in control. Figure 1 shows the phases and stages within the adaptive AI-DLC workflow. The stages shown in green boxes are mandatory, while those in yellow boxes are conditional.
Figure 1. SDLC phases and stages in AI-DLC workflow
The AI-DLC workflow generates various Mermaid diagrams in markdown files. To view these diagrams within your IDE, you can install a Mermaid viewer plugin.
Let’s Begin Building!
Let’s construct a simple River Crossing Puzzle as a web UI app using AI-DLC. By choosing a straightforward app, we can concentrate more on learning the AI-DLC workflow and less on the project’s technical intricacies.
The sections below outline the individual steps in the AI-DLC development process using Amazon Q Developer. We’ll showcase screenshots of our IDE with the Amazon Q Developer plug-in and demonstrate how to interact with the workflow.
Although we’ve used the Amazon Q Developer IDE plug-in in this blog post, you can also use Kiro Command Line Interface (CLI) to build with AI-DLC without any additional setup. The workflow remains the same, except that you’ll interact through the command line instead of the graphical interface in the IDE.
As we progress through the workflow, your AI-DLC experience will be tailored to your specific problem statement. You’ll also notice the probabilistic nature of large language models (LLMs), as the questions and artifacts generated by them will vary from one run to another for the same problem statement. For example, if you attempt to replicate the same problem statement we used in this blog post, your experience will likely differ. This is expected and desirable. Despite these minor variations, we’ll eventually find a solution to the problem we initially set out to address.
Step 2: Load Q Developer Rules in your project workspace
Follow the README.md instructions in the GitHub repo to copy the rules files over to your project folder.
Step 3: Install and authenticate Amazon Q Developer Extension in IDE
Open the project folder you created in Step 2 in VS Code. Open the Amazon Q Chat Panel in the IDE and ensure that the AI-DLC workflow rules are loaded in Q Developer, as shown in Figure 2. If you don’t see what’s shown in Figure 2, please double-check the steps you performed in Step 2.
Figure 2: AI-DLC rules enabling in Amazon Q Developer
Step 4: Start the AI-DLC workflow by entering a high-level problem statement
Our development environment is now set up, and we’re ready to begin application development using AI-DLC. In our Q Developer chat session, we enter the following problem statement:
Using AI-DLC let's build a web application to solve the river crossing puzzle.
Notice that we’ve prefixed our problem statement with “Using AI-DLC …” to ensure that Q Developer engages the AI-DLC workflow. Figure 3 shows what happens next. The AI-DLC workflow is triggered within Q Developer. It greets us with a welcome message and provides a brief overview of the AI-DLC methodology.
Figure 3 shows an expanded view of the AI-DLC workflow rules folder structure on the left. You’ll notice that a single aws-aidlc-rules/core-workflow.md is placed in the designated.amazonq/rules folder, while the rest of the rules files are placed in an ordinary aws-aidlc-rule-details folder. This arrangement is designed to optimize model efficiency. By placing the aws-aidlc-rules/core-workflow.md file in the .amazonq/rules folder, , it serves as additional context, ensuring that the core workflow structure is always accessible without incurring additional token consumption. Conversely, the detailed phase and stage-level behavior rules are stored in the aws-aidlc-rule-details folder and are dynamically loaded as required. This approach conserves Amazon Q’s context window and token usage by retaining only the necessary information within the context at any given time, thereby enhancing model efficiency.
The rules files under the aws-aidlc-rule-details folder are organized into three sub-folders, each representing a phase of AI-DLC. Within each phase, there are stage-specific files. A common folder houses cross-cutting rules applicable to all AI-DLC phases and stages such as the “human-in-the-loop”.
The AI-DLC workflow is self-guided and provides us with a clear understanding of what to expect next. It informs us that it will enter the AI-DLC Inception phase next, starting with the Workspace Detection stage within it.
Figure 3: User enters high level problem statement in Amazon Q. AI-DLC workflow is triggered.
Step 5: Workspace Detection
We enter the Workspace Detection stage within the Inception phase. In this stage, AI-DLC analyzes the current workspace and determines whether it’s a greenfield (new) or brownfield (existing) application. Since AI-DLC is an adaptive workflow, it decides whether the next stage will be Reverse Engineering (for brownfield projects) or Requirements Analysis (for greenfield projects).
Since we’re building a greenfield application and there’s no existing code in the workspace to reverse engineer, the workflow will guide us to Requirements Analysis next. If we were working on a brownfield application, the workflow would have performed Reverse Engineering first and then moved on to Requirements Analysis. This demonstrates the adaptive nature of the workflow.
Figure 4 illustrates the process in our IDE when we enter this stage. The workflow requests our permission to create an aidlc-docs folder under the project root. This folder will serve as the repository for all the artifacts generated by AI-DLC during the workflow execution. Subsequently, the workflow generates two files within this folder: aidlc-state.md and audit.md. The purpose of these files is explained in Figure 4.
Figure 4: Workspace Detection
The Workspace Detection will quickly finish as this is a greenfield project. The workflow will guide us into Requirements Analysis stage within the Inception phase next.
Step 6: Requirements Analysis
The workflow has progressed to the Requirements Analysis stage, where we will define the application requirements. The AI-DLC workflow presented our high-level problem statement to the Q Developer, which then responded with several requirements clarifications questions, as illustrated in Figure 4.
Several AI-DLC rules came into play at this stage. One rule instructed Amazon Q to avoid making assumptions on the user’s behalf and instead ask clarifying questions. Since LLMs tend to make assumptions and rush towards outcomes, they must be explicitly instructed to align with the engineering rigor of the AI-DLC methodology. To achieve this, the Q Developer presented several requirements clarification questions in requirement-verification-questions.md file and asked us to answer them inline in the file.
Another AI-DLC rule instructed the Q Developer to present questions in multiple-choice format and always include an open-ended option (“Other”) to enhance user convenience and provide flexibility in answering.
As shown in Figure 5, Amazon Q has asked us about the desired puzzle variant, such as the Classic Farmer, Fox, Chicken, and Grain puzzle or other popular variations. Additionally, it has asked us questions about user interaction methods, score persistence across multiple players, and the creation of a leaderboard.
These questions are essential for achieving our desired application outcome. Our responses to these questions will determine the final product. While we didn’t explicitly specify this level of detail in our high-level problem statement, AI-DLC has delegated detailed requirements elaboration to Amazon Q, but we still retain control over what gets built.
Figure 5: Requirements Analysis
We answer all the questions in requirement-verification-questions.md file and enter “Done” in the chat window.
Amazon Q processes our responses. The AI-DLC workflow is designed to identify human errors. It checks if we’ve answered all the questions and identifies any contradictions or ambiguities in our answers. Any confusions, contradictions, or ambiguities will be flagged for follow-up questions. AI-DLC adheres to high standards and ensures that we don’t proceed to the next step until we’re fully in agreement on the requirements between us and Amazon Q.
Since we answered all the questions and there were no contradictions in our answers, the workflow continues and generates a comprehensive requirements.md document, as shown in figure 6.
Figure 6: Requirements Review
The workflow prompts us to review the requirements.md document and decide on the next step. If we’re not aligned on the requirements, we can prompt Amazon Q to help us achieve alignment. We can then iterate on the requirements until we’re fully aligned. Once we’re fully aligned, we prompt AI-DLC to progress to the next stage.
Given the adaptive nature of the AI-DLC workflow, Amazon Q has recommended that this application is simple enough, and we can skip the User Stories stage. If we felt otherwise, we would have overridden the model’s recommendation. In this case, we agree with Q’s recommendation and will therefore enter “Continue” in the chat window.
The workflow will enter Workflow Planning stage next.
Step 7: Workflow Planning
With our requirements established, we proceed to the Workflow Planning stage. In this phase, we leverage the requirements context and the workflow’s intelligence to plan the execution of specific stages of AI-DLC within the workflow to build our application as per the requirements specification.
Figure 7 illustrates the workflow planning stage in Q Developer. The workflow has generated an execution-plan.md file that outlines the recommended stages for execution and those that should be skipped.
The workflow planning process is highly contextual to the requirements. During requirements analysis, we decided to develop a simple river crossing puzzle application, consisting of a single HTML file, without a backend, leaderboard, or persistence. Consequently, Amazon Q recommends that we skip all the conditional stages, such as User Stories, Application Design, Units of Work Planning, and so on, and proceed directly to the Code Generation Planning stage in the Construction phase.
Figure 7 visually represents the recommended workflow graphically, indicating the stages that will be executed and those that will be skipped.
Figure 7: Workflow Planning
Since we’ve opted for a straightforward web UI app in this blog post for brevity, the workflow execution plan suggested by AI-DLC aligns seamlessly with our objectives. Should we not be aligned with the AI-DLC recommended workflow execution plan, we would request Q Developer to modify the plan to suit our preferences.
Since we’ve agreed on the workflow plan, we’ll enter “Continue” in Q’s chat session. If we weren’t aligned with the recommended workflow execution plan, we’d have prompted Q with our concerns and iterated over the revised execution plan until it aligned with our preferences. Following the recommended execution plan, the workflow will transition into the Construction phase and directly into the Code Generation Plan stage in the phase.
Step 8: Code Generation Planning
AI-DLC prioritizes planning over rushing to outcomes. This approach aligns with the concept of human-in-the-loop behavior, allowing us to detect issues early on, provide feedback on the plan, and prevent wrong assumptions from propagating further. Before we proceed with actual Code Generation, we undergo Code Generation Planning.
During Code Generation Planning, AI-DLC creates a detailed, numbered plan. It analyzes the requirements and design artifacts, breaking down the process into explicit steps for generating business logic, the API layer, the data layer, tests, documentation, and deployment files.
The plan is documented in a {unit-name}-code-generation-plan.md file, complete with check boxes. This ensures transparency, allowing users to see what will be built. It also provides control, enabling users to modify the plan. Additionally, it maintains quality by ensuring comprehensive coverage of code, tests, and documentation.
Figure 8 illustrates the AI-DLC’s code generation plan. The proposed workflow comprises eight steps, starting with creating an HTML structure and progressing to adding styling, game logic, and concluding with testing and documentation.
Figure 8: Code Generation Planning
The code generation plan appears reasonable to us. We will proceed to the Code Generation stage by entering “Continue” in Q’s chat session.
Step 9: Code Generation
The Code Generation stage executes the Code Generation Plan we approved in the previous step. It generates actual code artifacts step-by-step, including business logic, APIs, data layers, tests, and documentation. Completed steps are marked with check boxes, progress is tracked, and story traceability is ensured before presenting the generated code for user approval.
Figure 9 illustrates that the Code Generation stage has been completed. We are now reviewing a single index.html file generated with embedded styling and JavaScript consistent with our preference specified in requirements.md.
The workflow provides a summary of the activities performed during the Code Generation phase.
Figure 9: Code Generation
We’re about to test our newly created application soon. While it may be straightforward to test this simple puzzle app right now, for complex applications, we generate build and test instructions using AI-DLC.
We’ll enter “Continue” in the workflow and enter the final Build and Test stage in the Construction phase.
Step 10: Build and Test
These questions are essential for achieving our desired application. We’ve reached the final stage of the AI-DLC Construction Phase, known as the Build and Test stage. During this stage, we create comprehensive instruction files that guide the build and packaging of the project, and document the necessary testing layers. These layers include unit tests (validating generated code), integration tests (checking unit interactions), performance tests (load/stress testing), and additional tests as required (security, contract, e2e).
The generated build instructions include dependencies and commands, test execution steps with expected results, and a summary document that provides an overview of the overall build/test status and the project’s readiness for deployment.
Figure 10 illustrates the documentation generated during this stage.
Figure 10: Build and Test
The AI-DLC workflow has now concluded.
Let’s Solve the Puzzle!
We open index.html in a web browser to access our newly created River Crossing Puzzle application. As shown in figure 11, we see our graphical web UI.
During requirements assessment, we chose a straightforward user interface using HTML, CSS, and JavaScript (without any frameworks), as evident in the display shown in Figure 11. Your display may vary due to the probabilistic nature of LLMs and the choices you made for requirements.
We attempt to solve the puzzle and find that it works as expected.
Figure 11: River Crossing Puzzle Web App
Conclusion
This post shows how AWS’s open-source AI-DLC workflow, guided by Amazon Q Developer’s Project Rules feature, helps developers build applications with structured oversight and transparency.
Using a River Crossing Puzzle web application as an example, the walk-through illustrates how AI-DLC methodology adapts its rigor based on project complexity, skipping unnecessary stages for simple applications while maintaining comprehensive processes for complex projects. Throughout each stage, AI-DLC enforces “human-in-the-loop” behavior, requiring user approval at critical checkpoints, asking clarifying questions, and maintaining complete audit trails for traceability.
The exercise successfully demonstrates how AI-DLC balances AI automation with human oversight, enhancing productivity without sacrificing quality or control. By following this structured, repeatable methodology, development teams can leverage generative AI’s capabilities while ensuring humans remain in charge of architectural decisions and implementation approaches. This framework provides the necessary guardrails for responsible and effective AI-assisted software development across projects of varying complexity.
Cleanup
We did not create any AWS resources in this walk-through, so no AWS cleanup is needed. You may cleanup your project workspace at your discretion.
AI-Driven Development Life Cycle (AI-DLC) holds the promise of unlocking the full potential of AI in software development. By emphasizing AI-led workflows and human-centric decision-making, AI-DLC can deliver velocity and quality. However, realizing these gains hinges on how organizations effectively integrate AI into their engineering workflows.
Through our work with engineering teams across industries, we have identified three recurring challenges. These challenges consistently limit the effectiveness of AI in accelerating modern software development. The first challenge is one-size-fits-all workflows. These workflows force every project through the same rigid sequence of steps. The second challenge is the lack of flexible depth in workflow stages. This leads to over-engineering or insufficient rigor. The third challenge is tools that over-automate. These tools unintentionally divert humans away from critical validation and oversight responsibilities.
Achieving true, sustainable productivity requires the process and AI coding agents to become adaptive to context, flexible in depth, and collaborative by design. In this blog, we’ll show you how AI-DLC’s core principles address these three challenges, transforming them from productivity blockers into opportunities for adaptive, human-centered development. We’ll describe how AI-DLC enables workflows that adapt to the problem at hand by intelligently selecting stages, modulating depth, and embedding human oversight at every critical decision point.
We will also introduce our open-sourceAmazon Q Developer/Kiro Rules implementation, which brings AI-DLC principles to life through adaptive workflow scaffolds. This allows you to start applying these principles in your own projects and experience AI-native development that accelerates delivery without compromising engineering discipline or human judgment.
How does AI-DLC address these challenges?
Let’s explore how AI-DLC addresses these challenges.
1. The “One-Size-Fits-All” Workflow Problem
Software development has never been a linear process. In practice, different projects follow distinct pathways with their own checkpoints and deliverables. Consider these examples:
A simple defect fix doesn’t require elaborate requirements analysis and planning
A pure infrastructure porting project doesn’t warrant application design with domain modeling
A new feature or service addition demands different steps than applying a security patch
Yet, many modern Agentic coding tools provide hard-wired, opinionated workflows that ignore this diversity. Regardless of intent or scope, every project is forced through the same rigid sequence of steps—even when some add little or no value. This rigidity introduces friction, wastes time, and reduces productivity. The result: artificial ceremonies, unnecessary artifacts, redundant approvals, and process overhead that impede velocity.
How AI-DLC addresses this challenge: AI-DLC addresses this challenge through the Principle 10 (No Hard-Wired, Opinionated SDLC Workflows) as defined in the AI-DLC Method Definition Paper.
“AI-DLC avoids prescribing opinionated workflows for different development pathways (such as new system development, refactoring, defect fixes, or microservice scaling). Instead, it adopts a truly AI-First approach where AI recommends the Level 1 Plan based on the given pathway intention.“
2. Lack of Flexible Depth Within Each Stage
True adaptivity must go beyond the breadth of a workflow and extend into its depth and intensity. This is how human experts intuitively plan software projects today.
Even when workflows are flexible, many tools fail to modulate the depth of engagement at each stage. For example, building a lightweight utility function doesn’t require full-scale Domain-Driven Design or detailed architectural modeling. When an AI coding agent compels teams to follow these steps regardless of need, the consequence is wasted effort and an over-engineered product. Developers spend cycles reviewing artifacts as the tools dictate rather than delivering business value.
How AI-DLC addresses this challenge: Through the same principle 10, AI-DLC adapts both the breadth (choice of stages) and the depth of each stage to match the complexity of the intent and context. For example, the complexity of the requirements determines whether a conceptual design is sufficient or whether a full architectural deep dive is required in the Design stage.
Humans validate and adjust this AI-proposed breadth and depth, ensuring that each stage’s rigor matches the scope of the challenge. This elasticity—balancing breadth and depth—is essential for sustaining true velocity without sacrificing engineering discipline.
3. Tools that Reduce the Emphasis on Human Oversight
As AI tools automate more of the Software Development Life Cycle (SDLC), a new risk has emerged: process atrophy. Developers, excited by automation, often drift into passive execution—allowing AI to “decide everything.” The result is a loss of reflection, weakened oversight, and erosion of shared understanding. AI tools must not only automate work but also amplify the significance of human judgment. They should remind practitioners that “human in the loop” is not a checkbox—it is the cornerstone of trust, accountability, and correctness in AI-native development. Equally critical are the rituals and rhythms that sustain collaborative engineering.
How AI-DLC addresses this challenge: AI-DLC addresses this challenge by requiring a collaborative human-in-the-loop cycle at every stage of the workflow. In this loop, AI generates a plan to execute a task, and relevant stakeholders assemble, review, and validate it.
These rituals, defined as Mob Elaboration and Mob Construction in AI-DLC, ensure that AI’s suggestions are not blindly accepted. Approved plans are executed, and stakeholders again review and validate the final artifacts. The AI-DLC workflow records every human action and approval, embedding reflection to ensure that humans remain the compass, guiding AI’s acceleration.
Figure 1: AI-DLC workflow: Humans decide and validate, AI plans and executes.
Effective tooling must therefore emphasize:
Promoting for stakeholder collaboration: The system should explicitly call for collaborative rituals involving stakeholders
Auditability: Every AI-generated plan and artifact should surface rationale and invite review, recording every human oversight and interaction
Flow awareness: Tools should detect when automation races ahead of human validation and deliberately slow down to emphasize critical checkpoints
The goal is not to suppress automation but to embed critical human ownership.
From Principles to Practice
The ideas we outlined — adaptive workflows, flexible depth, and embedded human oversight — are compelling in theory and validated by all engineering teams we’ve engaged. The critical question is: How do we operationalize these ideas into practice without reintroducing the rigidity we seek to eliminate?
One approach is manual prompt engineering: crafting structured prompts that guide AI assistants through the AI-DLC workflow step by step. Each prompt encodes the role AI should assume, the task at hand, the governance requirements, and the audit trail expectations. This structured approach transforms a simple AI interaction into a disciplined workflow that embodies AI-DLC principles.
This approach, while promising, faces its own limitations. Crafting intricate prompts demands discipline and expertise, posing barriers to widespread adoption. Moreover, humans become responsible for maintaining workflow adaptability, selecting the appropriate prompt at the right moment, and ensuring collaborative checkpoints are honored. This places the burden of orchestration back on practitioners, diverging from our core principle of truly AI-native development, where AI itself drives adaptive decision-making.
The question arises: How can we embed AI-DLC principles directly into the execution layer, making adaptivity and collaboration inherent properties of the system rather than manual responsibilities?
Steering for Productivity
The answer lies in workflow scaffolds. These are Rules or Steering customizations for AI Coding Agents. They operationalize AI-DLC principles within the tools. This is done while maintaining transparency, audibility, and modifiability. Our implementation uses Rules/Steering Files. These serve as the foundation of this execution layer. It transforms AI from a passive assistant into an adaptive decision engine.
Rather than requiring developers to craft elaborate prompts, AI-Driven development begins with a simple statement of intent. From there, the workflow scaffolds evaluate context, assess complexity, and dynamically construct an appropriate development pathway. The core workflow definition, including a library of stages and decision heuristics for when and how to apply them, empowers AI to continuously tailor the development process to the nature of the work at hand.
Each AI-DLC phase (Inception, Construction, Operations) evaluates the depth at which it should execute, resulting in a process that adapts to the problem rather than forcing the problem to adapt to the process. This approach yields several critical outcomes:
Adaptive decisioning: The workflow conforms to the problem’s shape, intelligently skipping or deepening stages based on contextual assessment rather than predetermined rules.
Transparent checkpoints: Human approvals are embedded at every decision gate, preserving oversight while maintaining velocity. The system doesn’t just automate; it orchestrates collaboration.
End-to-end traceability: Every artifact, decision, and conversation is logged, creating a continuous, inspectable trail of reasoning that supports both accountability and continuous improvement.
The result is a process that is context-aware, scalable, and self-correcting – capable of supporting everything from a single-line defect fix to a comprehensive system modernization, all while maintaining the rigor and human judgment that define engineering excellence.
Build, Test, and Evolve with Us
We’re open-sourcing the AI-DLC workflow, implemented as Amazon Q Rules and Kiro Steering Files, so organizations everywhere can experience AI-DLC in practice and build production-grade systems. We invite developers, architects, and engineering leaders to:
Apply the steering rules in real-world projects, whether brownfield or greenfield. Refer to our companion AI-DLC workflow walkthrough blog for step-by-step instructions on how to build using AI-DLC in Amazon Q Developer.
Observe how the process adapts to your project’s size, scope, and intent.
Share your experience through our GitHub repository, where you can open issues, propose improvements, and contribute ideas.
Your feedback will help evolve this into a foundation for AI-native software development – one that accelerates delivery without sacrificing rigor or human judgment. Together, we can redefine what software engineering looks like in the age of AI: not scripted but steered.
Conclusion
AI-DLC addresses multiple challenges limiting AI’s effectiveness in software development such as rigid workflows, inflexible workflow depth, and tools that reduce human oversight. AI-DLC enables adaptive workflows that intelligently select stages, modulate depth, and embed human oversight at critical decision points. This approach, implemented through open-source tools like Amazon Q Developer Rules and Kiro Steering, accelerates delivery while maintaining engineering discipline and human judgment.
AI-DLC emphasizes human oversight and collaboration in AI-driven software development. Workflow scaffolds, embed AI-DLC principles into the execution layer, enabling adaptive decision-making, transparent checkpoints, and end-to-end traceability. Open-sourcing the AI-DLC workflow allows organizations to experience AI-DLC in practice and contribute to its evolution.
Ready to get started? Visit our GitHub repository to download the AI-DLC workflow and join the AI-Native Builders Community to contribute to the future of software development.
Audible, an Amazon company, is a leading producer and provider of audio storytelling. With a vast library of over 1,000,000 titles including audiobooks, podcasts, and Audible Originals with specific curated offerings available in each marketplace, Audible makes it easy to transform everyday moments into extraordinary opportunities for learning, imagination, and entertainment through immersive audio experiences. Robust testing is critical to ensure millions of end users enjoy a seamless experience across devices.
Remember the last time you inherited a software application codebase with minimal test coverage? Or perhaps you’ve written code in a rush to meet a deadline, promising yourself you’d add tests “later”? We’ve all been there. Testing is crucial but can often gets deprioritized when deadlines loom. That’s where Amazon Q Developer‘s agentic workflows come in, transforming the way developers approach test generation. This blog explores how Audible used Amazon Q Developer to boost their unit test coverage.
Business Use Case for Software Testing
In high velocity development environments, testing cycles can often times get compressed under tight deadlines, increasing quality risks. Amazon Q Developer transforms this paradigm by accelerating testing while maintaining comprehensive standards. Through automated test generation, edge case identification, and fix suggestions, teams execute thorough testing in reduced timeframes, delivering expedited releases, optimized QA resources, and enhanced production readiness.
Each function that does not have the appropriate testing implemented, represents the potential for a rework, bugs, and maintenance challenges. Additionally, inherited codebases present particular challenges: developers must choose between spending weeks writing tests for existing functionality or continuing the cycle of untested code.
Amazon Q Developer addresses these challenges by reducing the time and effort required for proper test coverage, transforming testing from a burdensome chore into a streamlined process that allows teams to focus on delivering new features while helping to ensure code quality.
Amazon Q Developer: Expanding test coverage for your codebase
Amazon Q Developer introduces an advanced approach to software testing generation through its agentic workflows. Unlike traditional test generation tools that produce generic tests, Amazon Q Developer analyzes your code’s intent, business logic, and edge cases. It doesn’t just generate tests; it creates meaningful test suites that validate your code’s behavior comprehensively.
Beyond the dedicated test generation workflow we’ll explore today, Amazon Q Developer offers multiple ways to assist with testing. You can use conversational prompts for test plan generation, request test improvements for existing code, or even pair-program with Amazon Q Developer as you write tests. The flexibility to integrate AI assistance throughout your testing workflow makes Amazon Q Developer a versatile companion for developers.
Amazon Q Developer workflow architecture
The following architecture diagram illustrates how Audible leveraged Amazon Q Developer for both test generation and code transformation:
The Amazon Q Developer workflow demonstrates two key capabilities:
Test Generation: Amazon Q Developer analyzes Java classes and creates comprehensive test suites including unit tests, edge case tests, and exception handling tests.
Code Transformation: Amazon Q Developer performs automated migration tasks including JDK 8 to JDK 17/21 upgrades, handling language version compatibility, JUnit 4 to JUnit 5 conversion, modernizing test framework syntax and annotations, syntax migration, updating deprecated APIs and code patterns.
What makes this workflow particularly powerful is how it combines AI capabilities with human expertise, allowing expert developers to leverage AI in their day-to-day workflow. Amazon Q Developer analyzes your codebase and uses it as a context, identifies edge cases, and performs automated transformations, while developers apply their domain knowledge to ensure the outputs align with business requirements and expected behavior.
Audible’s Approach to harness the potential of Amazon Q Developer
The Audible teams followed the below steps to harness Amazon Q Developer to boost test coverage.
Code Submission: The Audible team leveraged Amazon Q Developer to enhance their test coverage by generating additional unit tests for Java classes, including static methods and methods with existing test cases. This approach complemented their robust testing strategy. Amazon Q Developer has the ability to examine classes, methods, parameters, return types, and exceptions. Amazon Q Developer is helpful in automatically identifying unit tests to cover edge cases that can easily be overlooked, such as null input checks and empty string checks.
Targeted Requests: The Audible team specifically asked Amazon Q Developer to provide:
Suggestions for unit tests to cover the given method within a Java class
Recommendations for unit tests targeting untested edge cases
Recommendations for test cases addressing error handling and exception scenarios
The Audible team achieved significant improvements using Amazon Q Developer for both test generation and code transformation. The key to their success was providing rich context along with targeted prompts in a systematic workflow.
Developer Workflow
Audible adopts a human in the loop approach to review the output from automation tools. The above workflow shows the complete process: (1) open a class file in their IDE, (2) select a specific method and add their prompt, (3) submit this combined context to Amazon Q Developer, (4) receive generated tests, and (5) review and integrate the tests into their codebase.
Effective Prompts and Approach
The Audible team followed a structured approach, using targeted requests that Amazon Q Developer could act upon:
Code Submission: The team provided Java classes to Amazon Q Developer with code to generate tests for individual methods, including static methods and those that already had some tests but lacked full coverage. Amazon Q Developer examined classes, methods, parameters, return types, and exceptions, automatically identifying unit tests to cover edge cases like null input checks and empty string checks.
Below are generic Sample Prompts for Specific Requests:
Basic Test Generation:
Generate unit tests for the following Java method. Focus on covering all possible input scenarios and edge cases:

[method code here]

Please include tests for:
- Valid input scenarios
- Null input checks
- Empty string validations
- Exception handling
Edge Case Focus:
I have this method that processes user input. Can you suggest unit tests that cover edge cases I might have missed? Pay special attention to boundary conditions and error scenarios:

[method code here]
Convert this JUnit 4 test to JUnit 5 format. Make sure to update annotations and use modern JUnit 5 features where appropriate:

[JUnit 4 test code here]
Note: While Amazon Q Developer’s code transformation feature can handle JUnit4 to JUnit5 migration automatically across entire codebases, Audible also used the conversational interface for manual, targeted conversions as shown above. Both approaches are available. Refer to documentation for automated transformation details.
Test Generation: Based on the team’s requests, Amazon Q Developer generated specific test suggestions addressing these areas with appropriate assertions and test methods.
Implementation: The development team implemented the suggested tests after review.
Documentation: Amazon Q Developer has the ability to add comments to explain the purpose of the test, area of the functionality that the test is covering. In addition, Amazon Q Developer also has the ability to generate documentation related to other aspects like read-me files and project documentation.
Quantifiable Results
By leveraging Amazon Q Developer, the Audible team achieved:
Over 10 key packages received comprehensive unit test coverage
~1 hour saved per test class (typically containing 8-10 individual tests)
5,000+ test cases successfully migrated from JUnit4 to JUnit5 using both Amazon Q Developer’s code transformation and manual conversational assistance
50+ hours of manual work saved during the JDK8 to JDK17 migration using Amazon Q Developer’s code transformation
Reduced human errors through AI-assisted transformations
Key Capabilities Demonstrated
Amazon Q Developer excelled in several areas that can be overlooked in manual testing:
Comprehensive Exception Testing: Beyond standard null input checks and empty string validations, it automatically suggested tests for IllegalArgumentException, NullPointerException, and custom business exceptions, including verification of both exception throwing and specific error messages. This systematic approach made test coverage more complete and error handling more robust.
Automated Edge Case Detection: Amazon Q Developer made inline suggestions for null pointer exception handling without prompting, making the process smoother and faster.
Manual Framework Migration with AI Assistance: Amazon Q Developer’s pattern recognition accelerated the migration process through conversational assistance. The team could ask Amazon Q Developer through the chat to convert test syntax from JUnit4 to JUnit5 manually. For example, their previous setup had JUnit4 syntax with @UseDataProvider and @DataProvider annotations. All they had to do was highlight the code block, Send to Prompt, and ask Amazon Q Developer to make the test JUnit5 compatible. Within seconds, it generated a reliable JUnit5 test with ParameterizedTest annotation and Stream of Arguments that they could manually implement.
Contextual Analysis: Amazon Q Developer analyzes the existing codebase and recognized patterns and generated tests that matched the team’s coding style and testing conventions.
Conclusion
Amazon Q Developer transforms the test generation process from a time-consuming chore into a streamlined workflow, enabling teams to achieve comprehensive test coverage with minimal effort. This allows developers to focus on higher-value activities while improving code quality and reliability.
The business impact is substantial: As testing becomes less burdensome, teams naturally adopt better testing practices, creating a positive feedback loop that enhances overall code quality, and creates an opportunity for faster development cycles, and reduced time spent on maintenance.
Kirankumar Chandrashekar is a Generative AI Specialist Solutions Architect at AWS, focusing on Next Generation Developer Experience tools like Q Developer, Kiro and Developer Productivity using AI. Bringing deep expertise in AWS cloud services, DevOps, modernization, and infrastructure as code, he helps customers accelerate their development cycles and elevate developer productivity through innovative AI-powered solutions. By leveraging Amazon Q Developer, he enables teams to build applications faster, automate routine tasks, and streamline development workflows. Kirankumar is dedicated to enhancing developer efficiency while solving complex customer challenges, and enjoys music, cooking, and traveling.
Alex Torres is a Senior Solutions Architect at AWS, supporting Amazon.com in architecting, designing, and building applications on AWS. With deep expertise in security, governance, and Agentic AI for developers, he helps customers leverage cutting-edge cloud technology to create products that shape people’s lives. Passionate about empowering teams to solve complex challenges through innovative AWS solutions, Alex is dedicated to driving customer success while maintaining the highest standards of security and governance. Outside of work, he enjoys cooking and hiking.
GK is a Senior Customer Solutions Manager and strategic customer advisor supporting Amazon as a customer of AWS. Over her four years at AWS, she has focused on improving developer productivity and advocating for Amazon’s needs across AWS services to enhance user experience and drive deeper alignment between the two organizations. Her work with advanced Amazon teams helps deliver solutions that ultimately benefit both internal and external AWS customers. GK is particularly interested in how GenAI is bridging the gap between developers and non-developers, and she spends much of her time solving challenges in GenAI and security. She is based in the San Francisco Bay Area and enjoys hiking and camping.
Aditi Joshi is a Software Engineer at Audible, working on expanding Audible’s presence across Amazon platforms. As a full-stack developer, she primarily works with web technologies, cloud services, and programming languages like JavaScript and Java to build and enhance cross-platform integration features, including recent projects like introducing Audible purchase capabilities in the Amazon iOS app. With expertise in user interface development, responsive design, and web technologies, she focuses on showcasing Audible offers and growing Audible’s visibility across Amazon’s ecosystem. Aditi is passionate about software architecture and user experience, focusing on building scalable systems with clean, efficient code. When not coding, Aditi enjoys traveling, practicing yoga, and listening to music.
Sam Park is a Software Development Engineer at Audible, focused on building Audible features across Amazon platforms. He has played a key role in enabling Audible purchases through Amazon Cart, as well as expanding Audible’s visibility within the Amazon iOS and Android apps. His work spans multiple touchpoints within the Amazon ecosystem, including Search, Product pages, Checkout, and Cart experiences. Sam is passionate about developing solutions that create intuitive customer experiences and leveraging GenAI to boost development efficiency and productivity. Outside of work, he enjoys traveling, playing basketball, and cheering on the Cleveland Cavaliers.
As organizations increasingly adopt AI-powered development tools, a critical challenge emerges: how do you maintain security governance when AI assistants execute AWS operations on behalf of users? Organizations want to leverage AI assistance for development and read operations while maintaining strict controls over write operations that impact production systems and auditing calls made via AI assistants. Consider this scenario: A developer asks Amazon Q Developer“List my S3 buckets”, Q Developer suggests aws s3 ls, the developer approves, and Q Developer executes the command via AWS CLI. From an AWS perspective, this looks identical to the developer manually running the aws s3 ls command on the terminal outside of Amazon Q Developer. But what if your organization needs to distinguish between AI-assisted operations and manual commands for governance or compliance?
Amazon Q Developer, the most capable generative AI–powered assistant for software development, generates AWS CLI commands in response to user requests and executes them using its use_aws and execute_bashbuilt-in tools. The challenge of distinguishing AI-assisted operations from manual commands is a key consideration for Amazon Q Developer adoption in enterprise environments. To address this governance challenge, Amazon Q Developer includes a built-in solution: user-agent markers that automatically identify AWS CLI calls made through Q Developer in CloudTrail logs, enabling precise IAM policy controls.
This blog post explores how Amazon Q Developer’s built-in user agent markers set for AWS CLI calls enable precise IAM policy controls, allowing organizations to distinguish and govern AI-assisted AWS operations while maintaining the productivity benefits of AI-powered development. The following sections demonstrate how these user agent markers work, how to implement IAM policies that leverage them, and how to monitor their effectiveness in your environment.
Understanding Amazon Q Developer User Agent Markers
Prerequisites
This section builds on your knowledge of these concepts and assumes you have the necessary setup in place. These foundational elements are essential for understanding how user agent markers work and for implementing the governance controls discussed later in this post. If you need guidance on any of these topics, please refer to the linked documentation:
Amazon Q Developer setup for CLI and/or IDE extensions – Needed to generate the user agent markers this post examines
AWS CloudTrail concepts and API logging – Essential for monitoring and verifying user agent markers in practice
IAM policies and permissions management – Critical for implementing the governance controls that leverage these markers
Amazon Q Developer automatically includes identifiable markers in the user agent string of all AWS API calls it makes via AWS CLI. These markers appear in two primary contexts: CLI tool operations and IDE integration operations.
Q Developer CLI Tool
When using Amazon Q Developer CLI (both use_aws and execute_bash tools), all AWS CLI calls include:
exec-env/AmazonQ-For-CLI-Version-<QCLI-VersionNo>
How It Works: Amazon Q Developer CLI automatically sets:
This means all AWS CLI commands executed through Q Developer CLI – whether via the use_aws tool or execute_bash commands – automatically include this marker.
This applies when Q Developer makes AWS API calls through IDE integrations, such as when analyzing your codebase or suggesting AWS resource configurations. The IDE marker enables you to distinguish between CLI-based and IDE-based Q Developer operations.
Complete User Agent Example
Here’s how a complete user agent string appears in CloudTrail:
The key identifiers are exec-env/AmazonQ-For-CLI-Version-* and exec-env/AmazonQ-For-IDE-Version-*, which clearly distinguish Amazon Q Developer operations from regular AWS CLI/SDK usage executed outside of Q Developer.
Use the aws:userAgent condition in IAM policies to control Amazon Q Developer operations through two approaches:
IAM Policies: Deploy in each AWS account where developers have access for deploying workloads or performing AWS operations. Q Developer operates using the developer’s existing AWS credentials and permissions – it doesn’t have additional access beyond what the user already possesses. Attach these policies to the same IAM users, groups, or roles that developers use for their regular AWS work.
Service Control Policies (SCPs): Deploy once at the AWS Organizations level for organization-wide governance. SCPs apply to all member accounts automatically and cannot be overridden by account-level policies.
The following policy allows read operations from Q Developer, blocks write operations from Q Developer, and allows write operations from regular AWS CLI executed outside Q Developer:
Note: This IAM policy example is for illustration purposes only. Follow least privilege principles in production environments. For more details refer prepare for least previlege permissions.
Note on User Agent Reliability: While AWS warns that user agents can be “spoofed,” this concern is reduced for Q Developer governance use cases. The user agent is automatically set by Q Developer’s tools, not manually controlled by users. Any spoofing would require deliberate effort and would be detectable through usage pattern analysis. This approach is designed for operational governance and policy differentiation, not as a sole security control.
Additional Control Layer: Custom Agent Configuration
For an additional layer of control, you can create a custom agent configuration that restricts which AWS services Amazon Q Developer can access using allowedServices and deniedServices parameters for the use_aws tool:
This custom agent configuration works in conjunction with IAM policies to provide defense-in-depth governance of AI-assisted AWS operations. For more details, refer to the agent configuration documentation.
Verification and Monitoring
CloudTrail Event Analysis
To verify that your policies are working correctly, examine CloudTrail events. Here’s what to look for:
Create a simple monitoring script to track Amazon Q Developer usage:
#!/bin/bash
# Monitor Amazon Q Developer AWS API usage
# Get events from last 24 hours and filter for Q Developer user agents
aws cloudtrail lookup-events \
  --start-time $(date -u -v-24H '+%Y-%m-%dT%H:%M:%SZ') \
  --lookup-attributes AttributeKey=EventName,AttributeValue=GetCallerIdentity \
  --query 'Events[?contains(CloudTrailEvent, `AmazonQ-For-CLI`)].[EventTime,EventName,UserIdentity.userName]' \
  --output table
Conclusion
Amazon Q Developer’s built-in user agent markers provide a powerful foundation for implementing enterprise-grade security controls around AI-assisted AWS operations. By leveraging these markers in IAM policies, organizations can:
Distinguish between AI-assisted and manual AWS operations
Implement differentiated security policies based on operation source
Maintain detailed audit trails for compliance requirements
Enable secure Amazon Q Developer adoption in enterprise environments while maintaining strict controls over write operations that could impact production systems
For organizations currently evaluating Amazon Q Developer adoption, implementing user agent marker-based controls is a key component of your deployment strategy. This approach enables you to realize the productivity benefits of AI-assisted development while maintaining the governance and security controls your organization requires.
Experience the power of Amazon Q Developer as your AI-powered coding assistant, and implement the governance controls outlined in this post to ensure secure adoption in your enterprise environment. These built-in user agent markers enable you to maintain enterprise-grade security while unlocking the productivity benefits of AI-assisted development.
Kirankumar Chandrashekar is a Generative AI Specialist Solutions Architect at AWS, focusing on Amazon Q Developer/Kiro and developer productivity. Bringing deep expertise in AWS cloud services, DevOps, modernization, and infrastructure as code, he helps customers accelerate their development cycles and elevate developer productivity through innovative AI-powered solutions. By leveraging Amazon Q Developer and Kiro, he enables teams to build applications faster, automate routine tasks, and streamline development workflows. Kirankumar is dedicated to enhancing developer efficiency while solving complex customer challenges, and enjoys music, cooking, and traveling.
As cloud adoption continues to accelerate, organizations are realizing that the journey to the cloud is just the beginning. The real challenge—and opportunity—lies in optimizing cloud usage to drive maximum business value. At AWS, we’re committed to helping our customers navigate this journey successfully. Let’s explore some key insights and best practices for cloud optimization from the recent MIT Technology Review publication, Driving business value by optimizing the cloud.
The cloud optimization imperative
Recent data shows that global cloud infrastructure spending reached $84 billion in Q3 2024, marking a 23% year-over-year increase. This growth underscores the critical role of the cloud in driving business agility and innovation. However, to truly harness the power of the cloud, organizations must strike the right balance between cost, security, resilience, and innovation.
André Dufour, AWS Director and General Manager for AWS Cloud Optimization, emphasizes that cloud optimization involves making cloud spending efficient so that freed-up resources can be redirected to fund new innovations, such as generative AI initiatives.
Cloud optimization should be viewed as a continuous process rather than a one-time event, requiring regular assessment whenever business conditions or technical requirements change significantly. The approach should be comprehensive, addressing not just costs but all six pillars (operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability), while also recognizing that different workloads require tailored optimization strategies rather than a one-size-fits-all approach.
Best practices for success
Consider the following best practices:
Upskill your team – Empower your employees with cloud, cost management, and optimization skills. As Dufour notes, “Every engineer or builder plays a role in cloud optimization.”
Establish a cloud center of excellence – Create a centralized body responsible for developing and distributing cloud best practices throughout your organization.
Align finance and business – Make cloud KPIs business-centric rather than purely technical, so cloud optimization efforts support overall business goals.
Embrace automation – Use tools to automate cloud provisioning, monitoring, and optimization, reducing human error and effort.
Use AI services and solutions for efficiency – Use AI technologies to automate visualization, enhance decision-making, and optimize resource utilization.
Real-world success stories
Our customers are already seeing significant benefits from strategic cloud optimization:
DreamCasino achieved 30% cost savings and a 50% reduction in API response times, enabling expansion into new markets
BMC Software reduced cloud costs by 25% while improving security and reliability, reinvesting savings into new business opportunities
Even within AWS, our use of Amazon Q for application modernization saved an estimated 4,500 years of development work and $260 million in performance benefits
Business impact
Effective cloud optimization delivers more than just cost savings. It enables the following:
Faster innovation through reinvestment of saved resources
Enhanced security and operational efficiency
Improved ability to scale and adapt to business needs
Better customer experiences and faster time-to-market
The capability to make informed architecture and design decisions by balancing trade-offs across AWS Well-Architected pillars
AWS resources for your optimization journey
To help you accelerate your cloud optimization efforts, AWS provides several tools and resources:
Use AWS re:Post as an authoritative, knowledge-sharing service designed to help you quickly remove technical roadblocks, accelerate innovation, and operate more efficiently
Additionally, you can engage with the AWS Cloud Optimization Success (COS) team for more detailed guidance and to help identify what to do next in your cloud optimization journey. The COS team has Solutions Architects who specialize in the Cloud Adoption Framework and Well-Architected Framework and deliver workshops and training sessions though customer and partner engagements. The team can help drive adoption of AWS services through the use of the Well-Architected and Cloud Adoption Frameworks and support other services like AWS Trusted Advisor and AWS Health to optimize cost and cloud architectures. Whether you’re just starting or looking to enhance existing implementations, the AWS COS team provides the guidance, tools, and expertise you need to succeed.
Conclusion
At AWS, we’re dedicated to helping you optimize your cloud journey. By implementing these strategies and best practices, you can unlock the full potential of the cloud, driving innovation and growth while maintaining security and operational excellence.
Ready to take your cloud optimization to the next level? Refer to the resources included in this post and contact your AWS COS team to learn how we can help you maximize the value of your cloud investments.
Amazon Q generative SQL brings generative AI capabilities to help speed up deriving insights from your Amazon Redshift data warehouses and AWS Glue Data Catalog, generating SQL for Amazon Redshift or Amazon Athena. With Amazon Q, you get SQL commands generated with your context. This means you can focus on deriving insights faster, rather than having to first learn potentially complex schemas. Without generative SQL, your data analysts might have to frequently switch between different types of SQL, which can further slow analysis down. Amazon Q generative SQL can help by generating SQL statements from natural language and speeding up development. This can help onboard analysts faster and improve analyst productivity. The generative SQL experience is available through Amazon SageMaker Unified Studio and Amazon Redshift Query Editor v2.
To scale the use of generative SQL in production scenarios, you need to consider how relevant and accurate SQL is generated. In doing so, it’s important to understand what data is used and how your information is protected. Amazon Q generative SQL is designed to keep your data secure and private. Your queries, data, and database schemas are not used to train generative AI foundation models (FMs). For more information, see Considerations when interacting with Amazon Q generative SQL.
In the post Write queries faster with Amazon Q generative SQL for Amazon Redshift, we provided general advice around getting started with generative SQL. In this post, we discuss the design and security controls in place when using generative SQL and its use in both SageMaker Unified Studio and Amazon Redshift Query Editor v2.
Solution overview
Generating relevant SQL requires context from your data warehouse or data catalog schemas. Your analysts can ask free text or natural language questions in the Amazon Q chat window and have SQL statements returned that reference your tables and columns. It’s important that the generated SQL is consistent with your schema so that it can find the most relevant fields to answer questions and generate queries that accurately reference data. In SageMaker Unified Studio or Amazon Redshift Query Editor v2, when the Amazon Q chat window is open, database metadata that is viewable under the connection context is made available to Amazon Q for SQL generation. This means that only the schema information that the connecting user can access is used. Tables or database objects the user doesn’t have access to are excluded.
When a user submits questions in the Amazon Q chat window, a search algorithm is used to find the most relevant context from the available database schema metadata information. This context is combined with the user’s question and used as a prompt to a large language model (LLM) to generate a SQL statement. The supporting information is cached so that your data source doesn’t need to be queried every time a user initiates SQL generation. Instead, data source metadata will be periodically refreshed if it remains in use, or you can trigger a manual refresh. If the data is not being used, Amazon Q will automatically delete it. Where applicable, the information used to support SQL generation is encrypted with an AWS Key Management Service (AWS KMS) customer managed KMS key where one has been specified in the SageMaker Unified Studio or Amazon Redshift Query Editor v2 settings. Otherwise, an AWS managed key is used. Your information is encrypted in transit and at rest.
The following diagram shows the process flow for SQL generation when using SageMaker Unified Studio or the Amazon Redshift Query Editor and using Amazon Redshift or Data Catalog source data.
The Amazon Q generative SQL process can be summarized as the following steps:
A user interacts with the Amazon Q chat pane through SageMaker Unified Studio or the Amazon Redshift Query Editor.
The SQL chat frontend sends the prompt along with the connection configuration to Amazon Q.
Amazon Q uses the connection context to retrieve information that will support SQL generation if this data is not already available.
Amazon Q encrypts the retrieved information under the appropriate AWS managed or customer managed KMS key. The information is subsequently decrypted on retrieval.
The information is stored along with custom context information, if this has been provided.
Relevant context from the combined information is selected and added to the user’s questions and sent to an LLM to generate a SQL statement, which is returned to the user.
The user can decide whether to run the statement and can provide feedback on usefulness and accuracy.
Additional context to enhance SQL generation
You can provide further context to supplement the database schema information, which can help improve the accuracy and relevancy of the generated SQL.
One option is to provide custom context. Custom context gives the option to specify instructions and extra information, such as descriptions of tables and columns. These descriptions can then be used to help the selection of relevant tables and attributes when generating SQL statements. This is particularly relevant when your schema uses more obscure naming that might not directly relate to business terms or uses non-standard abbreviations. For example, consider a table called sls_r1_2024. With custom context, you can add a table description specifying that, for example, the table includes sales information across stores in the US region for the calendar year 2024. This information can help the LLM generate SQL referencing the correct tables. The same approach can be applied to columns within the table. Your custom context is encrypted using a customer managed KMS key if one has been specified (during Amazon Redshift Query Editor account creation or SageMaker Unified Studio project creation) or an AWS managed key otherwise.
You can also introduce constraints using custom context. For example, you can explicitly include or exclude specific schemas, tables, or columns from SQL query generation. Similarly, specific topics can also be disallowed, such as not generating SQL statements to support financial reporting. For more details about the information that can be supplied, refer to Custom context.
Another option is to grant SQL query history access to the user establishing the connection. This information is then also made available to enhance SQL generation and to provide the LLM with examples of relevant queries. Be aware that granting wider SQL query history access to the connecting user, and therefore also the generative SQL workflow, allows viewing of queries over tables or objects the user might not have access to. Furthermore, string literals might be present in historic statements that might contain sensitive information. To help mitigate this risk, you could instead use the CuratedQueries section of custom context to provide predefined question and answer examples, without exposing all user queries.
Generated statement response
Before a SQL statement is returned to the user, Amazon Q tries to detect syntax issues. This step helps improve the likelihood that only valid SQL syntax is returned. Amazon Q will use the available information for the user to return statements that align with user permissions, to reduce scenarios where users can’t run generated statements. For example, if you have given access to SQL query history information, then the SQL generation step might produce a query statement referencing a table that the user asking the question doesn’t have access to. Amazon Q minimizes the occurrence of this scenario by assessing if the generated SQL aligns with user permissions and updating the statement if not. User permissions are not bypassed through the use of Amazon Q generative SQL. If a statement was returned referencing a table the user doesn’t have access to, the authorization applied to the user will enforce access control when the statement is executed.
Statements generated by Amazon Q that could potentially change your database, such as DML or DDL statements, are returned with a warning. The warning highlights to the user that running the statement could potentially modify the database. Again, these statements are only executable if the user has the required permissions.
Prerequisites
Amazon Q generative SQL works with your Redshift data warehouses and Data Catalog tables. To get started, you should have data available in either or both of these environments. To use Amazon Q generative SQL with your AWS Glue tables, you need a SageMaker Unified Studio domain. Within your domain, you can use the Amazon Q chat integration to ask questions of your data and have SQL generated. This also works for Amazon Redshift data sources available in the domain. You can use Amazon Q generative SQL without a SageMaker Unified Studio domain using the Amazon Redshift Query Editor. Access to the editor enables Amazon Q chat integration against your Amazon Redshift data sources.
Enable Amazon Q generative SQL
You can control access to generative SQL at the account-Region level in the Amazon Redshift Query Editor or at the SageMaker Unified Studio domain level. To enable this feature, an account admin must explicitly turn on Amazon Q generative SQL. By default, the feature is not accessible to your users. Administrators that have permission for the sqlworkbench:UpdateAccountQSqlSettingsAWS Identity and Access Management (IAM) action can turn the Amazon Q generation SQL feature on or off through the admin window, as illustrated in the following sections. When turned off, this will restrict users from opening the Amazon Q chat pane and help prevent interaction with generative SQL.
Enable Amazon Q in your SageMaker domain
To enable Amazon Q in your SageMaker domain, you can navigate to the Amazon Q tab on the domain settings page and choose to enable the service. For more information, see Amazon Q in Amazon SageMaker Unified Studio.
Enable Amazon Q in Amazon Redshift
To enable Amazon Q generative SQL from the Amazon Redshift Query Editor, access the Amazon Q generative SQL settings. This requires the administrator to have the sqlworkbench:UpdateAccountQSqlSettings permission in their IAM policy. For more information, see Updating generative SQL settings as an administrator.
With generative SQL enabled at the account-Region level, you can restrict access to specific users with IAM controls. IAM administrators can build IAM policies that allow or deny access to the action sqlworkbench:GetQSqlRecommendations. For more information, refer to Actions, resources, and condition keys for AWS SQL Workbench. Policies can then be associated with IAM users or roles to control access to SQL generation at a more granular level. An appropriately scoped service control policy (SCP) can be used to limit access to SQL generation to specific accounts within your organization if required.
The following is an example policy denying access to use SQL generation:
Amazon Q Developer uses cross-Region inference to distribute traffic across different AWS Regions, which provides increased throughput and resilience during high demand periods, improved performance, and access to the latest Amazon Q Developer capabilities.
When a request is made from an Amazon Q Developer profile, it is kept within the Regions in the same geography as the original data. Although this doesn’t change where the data is stored, the requests and output results might move across Regions during the inference process. Data is encrypted when transmitted across Amazon’s network. For more information on cross-Region inference, see Cross-region processing in Amazon Q Developer.
Monitoring
To monitor which IAM users or roles are interacting with generative SQL, you can use AWS CloudTrail. CloudTrail monitors API calls and logs which identities have performed particular actions. When a user first asks a question, a CloudTrail event is emitted called IngestQSqlMetadata. This is a result of Amazon Q starting the metadata ingest process. Ingestion is an asynchronous operation, so there might be a series of GetQSqlMetadataStatus events. This is due to the workflow checking the ingestion process status.
After the workflow has completed successfully, each question sees a GetQSqlRecommendation event. This is the result of users submitting questions and triggering generation of SQL statements. The following is an example CloudTrail event for GetQSqlRecommendation. In this example, Amazon Q emits detailed CloudTrail events highlighting the warehouse being queried, IAM principal calling Amazon Q, and the entire response structure from Amazon Q in responseElements:
In this post, we discussed the Amazon Q generative SQL workflow. We highlighted the process around using your schema context alongside metadata such as historic SQL queries and custom context. Using this metadata allows the generation of relevant SQL that helps accelerate your analyst’s productivity. Although it’s important to assist analysts, it’s also imperative to make sure data remains secure and protected. To support this, generative SQL uses only the data the connected user has access to. This helps prevent exposure to information beyond their authorization.When you’re looking to increase the relevance of generated SQL through sharing additional query history, it’s important to consider the trade-off of exposing additional information to the user. Deciding your approach here should take into account the domain context of the data and the possible exposure of metadata the user doesn’t have access to, or potentially sensitive information that might appear in query strings. Keeping these considerations in mind can help you achieve the appropriate security posture for your workloads.
Gregory Knowles is a data and AI specialist solution architect at AWS, focusing on the UK public sector. With extensive experience in cloud-based architectures, Greg guides public sector customers in implementing modern data solutions. His expertise spans governance, analytics, and AI/ML. Greg’s passion lies in accelerating transformation and innovation to improve productivity and outcomes. He has successfully led projects that moved data systems into the cloud, adopted new data architectures, and implemented AI at scale in production.
Abhinav Tripathy is a Software Engineer and Security Guardian at AWS, where he develops Amazon Q generative SQL by combining machine learning, databases, and web systems. Abhinav is passionate about building scalable web systems from scratch that solve real customer challenges. Outside of work, he enjoys traveling, watching soccer, and playing badminton.
Erol Murtezaoglu is a Technical Product Manager at AWS, is an inquisitive and enthusiastic thinker with a drive for self-improvement and learning. He has a strong and proven technical background in software development and architecture, balanced with a drive to deliver commercially successful products. Erol highly values the process of understanding customer needs and problems, in order to deliver solutions that exceed expectations.
ArgoCD is a leading GitOps tool that empowers teams to manage Kubernetes deployments declaratively, using Git as the single source of truth. Its robust feature set, including automated sync, rollback support, drift detection, advanced deployment strategies, RBAC integration, and multi-cluster support, makes it a go-to solution for Kubernetes application delivery. However, as organizations scale, several pain points and operational challenges become apparent.
Pain Points with Traditional ArgoCD Usage
ArgoCD’s UI and CLI are designed for users with extensive technical background. Interacting with YAML manifests, understanding Kubernetes resource relationships, and troubleshooting sync errors require specialized knowledge. This limits access to GitOps workflows for less technical stakeholders and increases reliance on DevOps engineers.
Managing ArgoCD across multiple clusters or environments (using hub-spoke, per-cluster, or grouped models) introduces significant operational complexity. Teams must handle multiple ArgoCD instances, maintain consistent configuration, and coordinate deployments, which can become a bottleneck as service footprints grow.
ArgoCD excels at syncing and monitoring Kubernetes resources but lacks built-in mechanisms for pre-deployment (e.g., image scanning) or post-deployment (e.g., load testing) tasks. This forces teams to rely on external tools or custom scripts, fragmenting the deployment pipeline and increasing maintenance effort.
Promoting applications across environments (Dev → Test → Prod) is not natively streamlined. Teams must manually orchestrate or script these promotions, slowing down urgent fixes and complicating the release process.
As organizations adopt multi-cluster strategies, managing ArgoCD’s access, RBAC, and resource visibility across environments becomes cumbersome, often leading to fragmented workflows and potential security gaps.
How ArgoCD MCP Server with Amazon Q CLI addresses these challenges:
The integration of the ArgoCD MCP (Model Context Protocol) Server with Amazon Q CLI fundamentally transforms the user experience by introducing natural language interaction for GitOps operations.
With MCP, users can manage deployments, monitor application states, and perform sync or rollback operations using plain conversational language rather than technical commands or YAML. For example, a user can simply ask, “What applications are out of sync in production?” or “Sync the api-service application,” and the system executes the appropriate ArgoCD API calls in the background.
This democratizes access to GitOps, enabling less technical team members (such as QA, product managers, or support engineers) to safely interact with deployment workflows.
Natural language interfaces abstract away the complexity of multi-cluster and multi-environment management. Users can query or act on resources across clusters without memorizing resource names, namespaces, or API endpoints.
The MCP server handles authentication, session management, and robust error handling, reducing the need for manual troubleshooting and custom scripting.
The integration provides detailed feedback, intelligent endpoint handling, and comprehensive error messages, making it easier to diagnose and resolve issues. Full static type checking and environment-based configuration further enhance reliability and maintainability.
By leveraging Amazon Q CLI’s extensibility, users gain access to pre-built integrations and context-aware prompts, accelerating development and deployment workflows.
The MCP server enables AI assistants and language models to automate routine tasks, recommend actions, and even debug issues, acting as a virtual DevOps engineer. This can significantly reduce manual effort and speed up incident response.
Traditional ArgoCD vs. ArgoCD MCP Server with Amazon Q CLI
Feature/Challenge
Traditional ArgoCD
With MCP Server + Amazon Q CLI
User Interface
Technical UI/CLI, YAML required
Natural language, conversational
Access for Non-Engineers
Limited
Broad, democratized
Multi-Cluster Management
Complex, manual
Simplified, abstracted
Pre-Post Deployment Tasks
External tools/scripts needed
(Still external, but easier to invoke)
Application Promotion
Manual or scripted
Natural language, easier orchestration
Troubleshooting
Technical, error-prone
Guided, AI-assisted, detailed feedback
Automation
Scripting required
AI/agent-driven, proactive
You can perform the following actions using natural language using Amazon Q CLI integration with ArgoCD MCP server.
Application Management: List, create, update, and delete ArgoCD applications
Sync Operations: Trigger sync operations and monitor their status
Resource Tree Visualization: View the hierarchy of resources managed by applications
Health Status Monitoring: Check the health of applications and their resources
Event Tracking: View events related to applications and resources
Log Access: Retrieve logs from application workloads
Resource Actions: Execute actions on resources managed by applications
Setting Up Your Environment
Pre-requisites
Following are the pre-requisites for setting up your EKS environment to be managed by ArgoCD using Amazon Q CLI.
An AWS account with appropriate permissions
AWS CLI v2.13.0 or later
Node.js v18.0.0 or later
npm v9.0.0 or later
Amazon Q CLI v1.0.0 or later (npm install -g @aws/amazon-q-cli)
An EKS cluster (v1.27 or later) with ArgoCD v2.8 or later installed
Once configured, you can start using natural language commands with Amazon Q CLI to interact with your ArgoCD applications.
Managing ArgoCD applications using natural language
Listed below are some example prompts to interact with ArgoCD applications in your EKS cluster.
List ArgoCD application
Prompt: “List all ArgoCD applications in my cluster”
Amazon Q will use the ArgoCD MCP server to retrieve and display all applications
Create new ArgoCD application
Prompt: Create new argocd application using App name: game-2048 Repo: https://github.com/aws-ia/terraform-aws-eks-blueprints Path: patterns/gitops/getting-started-argocd/k8s. Branch: main Namespace: argocd
Amazon Q will create a new application from GitRepo information provided
Viewing deployment status
Prompt: “Show me the resource tree for team-carmen app”
Amazon Q will display the hierarchy of Kubernetes resources managed by the application
Synchronizing applications
Prompt: “Show me the applications that’s out of sync”
Amazon Q will display the out of sync applications
Prompt: “Sync the application”
Amazon Q syncing application
Amazon Q will:
Initiate a sync operation for the specified application
Monitor the sync progress
Report the final status of the sync operation
Healthchecks and monitoring
Prompt:”Check the health of all resources in the team-geordie application”
Amazon Q showing health status of all the resources in an application
Amazon Q will:
Retrieve the health status of all resources
Identify any unhealthy components
Provide recommendations for addressing issues
Prompt: “Show me the logs for the failing pod in the team-platform application”
Amazon Q showing logs of problematic pod
Amazon Q will:
Identify problematic pods
Retrieve and display relevant logs
Highlight potential error messages
Conclusion
The integration of Amazon Q CLI with ArgoCD through the MCP server marks a transformative advancement in Kubernetes management, combining ArgoCD’s GitOps capabilities with Amazon Q’s natural language processing. By transforming complex Kubernetes operations into simple conversational interactions, this solution allows teams to focus on what truly matters – creating value for their business. Rather than spending time memorizing commands or navigating technical complexities, teams can now manage their cloud infrastructure through natural dialogue, making the cloud-native journey more accessible and efficient for everyone.Ready to transform your EKS and ArgoCD experience? It’s highly recommended to try out Amazon Q CLI integration with ArgoCD MCP and discover why DevOps teams are making it an essential part of their toolkit.
About the authors
Jagdish Komakula is a passionate Sr. Delivery Consultant working with AWS Professional Services. With over two decades of experience in Information Technology, he helped numerous enterprise clients successfully navigate their digital transformation journeys and cloud adoption initiatives.
Aditya Ambati, Is an experienced DevOps Engineer with 12 plus years of experience in IT. Excellent reputation for resolving problems, improving customer satisfaction, and driving overall operational improvements.
Anand Krishna Varanasi, is a seasoned AWS builder and architect who began his career over 16 years ago. He guides customers with cutting-edge cloud technology migration strategies (the 7 Rs) and modernization. He is very passionate about the role that technology plays in bridging the present with all the possibilities for our future.
As organizations scale their development efforts, AI coding assistants that understand organization-specific patterns and standards lead to more efficient development processes and higher quality software delivery. Amazon Q Developer Pro helps address this challenge by allowing organizations to customize the AI assistant with their proprietary code and development practices. Through Amazon Q Developer profiles, teams can efficiently manage access to Amazon Q customizations across different regions and AWS Identity Centers.
In this post, we will explore different approaches for implementing and managing Amazon Q Developer profiles and Amazon Q customizations across large organizations. Using an example with multiple business units, we will explore methods for managing access controls and customization governance while addressing security and compliance requirements.
Amazon Q customization is now available in both the US East (N. Virginia) and EU Central (Frankfurt) regions, giving teams more flexibility to create and deploy customizations closer to their operational hubs while meeting regional data residency requirements.
This blog is not intended to provide recommendations on how to structure your AWS accounts or divide Q Developer subscriptions. Rather, our aim is to explore the full capabilities of Q Developer Customizations in a comprehensive scenario that shows the current art of the possible.
A distributed Amazon Q Developer Pro subscriptions scenario
The following diagram illustrates a sample AWS Organizations structure with a Management Account and four Organizational Units (OUs). This is a common enterprise scenario with three business units, each business unit requiring their own Amazon Q Developer Pro subscription and customizations.
Figure 1: AWS Organizations Structure and Resource Hierarchy
The Infrastructure OU has a Delegated Admin Account with delegated access to the AWS IAM Identity Center. There are three additional OUs: Alpha, Bravo, and Charlie, each with at least one Amazon Q Developer Pro subscription. Alpha account has Amazon Q Developer subscriptions both in US East (N. Virginia) and EU Central (Frankfurt) region.
Think of each business unit as its own ecosystem within your organization. When you provide dedicated Q Developer Pro subscriptions to different OUs, you’re essentially giving each unit its own personalized AI assistant. This separation is valuable because it allows each team to work independently while maintaining their specific requirements and workflows.
The Charlie OU maintains its own account instance of IAM Identity Center for Amazon Q Developer Pro. In most cases, we recommend using an organization instance of IAM Identity Center with Amazon Q Developer Pro, there are a few situations where member account instances might make sense, for example: when you do not have a single identity provider, or when you haven’t yet decided to deploy it to the whole organization and want to use Amazon Q just for the AWS account you control.
Note: When a developer has a user within an Amazon Q profile tied to two different IAM Identity Center instances (Bravo and Charlie), they will have two user subscriptions and be billed twice. However, if they belong to two different Amazon Q profiles in two different accounts (Alpha and Bravo) but under the same IAM Identity Center, they will only be billed once.
In our example, the Charlie OU requires additional operational overhead in managing separate credentials and authentication flows. Additionally, the dashboard and administrative settings will only be associated with users and groups within this account. From an administrative perspective, instead of trying to manage one centralized configuration that attempts to serve everyone’s needs, you can distribute administration to each business unit and delegate responsibility to individual teams.
It’s like having different specialized departments in a hospital – while they’re all part of the same organization and can work together when needed, each department has its own specialized tools and protocols that help them perform their specific functions more effectively.
A strategic approach to Customizations through Q Developer profiles
Figure 2 Developers association to Amazon Q Developer Pro Subscriptions, Customizations and IAM Identity Centers
Amazon Q Developer profiles are the way developers connect to different Amazon Q Developer subscriptions through their IDE. Each profile represents a unique combination of an Amazon Q Developer subscription and its associated customizations. After authentication, developers can simply select or switch between profiles in their IDE to access different customizations.
Let’s walk through some scenarios in this architecture.
Scenario 1 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account
Developers from the Orange team with access to Alpha account customizations can configure two different Amazon Q Developer profiles in their IDE:
A “US Profile” connected to the US East subscription in the Alpha account
An “EU Profile” connected to the EU Central subscription in the Alpha account
Switching between different sets of customizations involves selecting the relevant profile within their IDE.
Figure 3 IDE showing customizations available for Team Orange developers switching between US and EU Profile and their customizations
Note: While developers can access multiple customizations through different Amazon Q Developer profiles, they only incur a single user subscription cost since they are using the organization instance of IAM Identity Center. This is because the subscription is tied to their user identity in the IAM Identity Center organization instance, not to the number of profiles or customizations they access.
Scenario 2 – Users accessing two different customizations tied to a single IAM Identity Instance in the management account Similarly, developers from the Blue team can also configure multiple profiles:
One profile for accessing Alpha and Bravo customizations through the management account AWS IAM Identity Center instance
A separate profile for accessing Charlie customizations through the AWS IAM Identity Center member account Instance
When developers have access to multiple customizations within the same IAM Identity Center configuration and region, they can switch between profiles in their IDE without requiring reauthentication.
Figure 4 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Organization
However, as demonstrated in the blue developers’ case, switching between profiles that use different IAM Identity Center configurations (Organization vs Account Instance) still requires reauthentication.
Note: In this scenario, developers will incur two separate user subscription charges since they are accessing customizations through two different IAM Identity Center configurations (organization and account instance). As mentioned above, this scenario is not recommended except for situations it might make sense and is shown here purely to illustrate how the authentication and profile switching mechanisms work across different IAM Identity Center configurations.
Figure 5 IDE showing customizations available for Team Blue developers when authenticated to AWS IAM Identity center Account Instance
One scenario for creating code customizations specific to each profile is that the developers on the Alpha team might need Q to understand specific libraries and internal coding conventions for Java, while Bravo team developers might need Q to be well-versed in your proprietary technologies and development standards with Python. With separate profiles and customizations, each team gets their own “flavored” version of Q that understands their context.
For Blue developers who have access to Alpha, Bravo and Charlie customizations, they need to set up separate profiles since these customizations belong to different IAM Identity Center configurations and AWS Regions. Switching between these profiles requires reauthentication due to the different IAM Identity Center configurations involved.
Developer Team
AWS IAM Identity Center
Customizations
Orange
Organization instance
Alpha customizations in US East (N. Virginia)
Alpha customizations in EU Central (Frankfurt)
Blue
Organization instance
Alpha customizations in US East (N. Virginia)
Bravo customizations
Account instance
Charlie customizations
Grey
Organization instance
Bravo customizations
You can manage access to specific Amazon Q Developer Pro customizations by adding selected users and groups who already have access to Amazon Q Developer Pro subscriptions within the same Identity Center. This granular access control allows you to create targeted customizations that are only accessible to specific team members or groups within your organization.
Conclusion
In this post, we explored comprehensive strategies for implementing Amazon Q Developer customizations across large organizations. We demonstrated how Amazon Q Developer profiles provide a flexible way to manage access to different customizations across AWS regions and IAM Identity Center configurations. By integrating proprietary code repositories, establishing customization governance, and implementing continuous feedback loops, enterprises can maximize the value of their AI-powered development assistant while maintaining code quality and development standards.
The path forward depends on where you are in your Amazon Q Developer customization journey. If you’re just starting, begin with a clear assessment of your codebase and map out your customization approach before implementation. For existing users, review your current customizations and profile configurations to identify optimization opportunities.
In both cases, implement the customization governance we discussed, tailoring them to your specific development patterns and team structures. Remember that customization evolves with your codebase – regular refinements help ensure your AI assistant remains effective as your applications grow and development practices mature. Whether you’re new to Amazon Q Developer customizations or optimizing existing implementations, these practices can help develop an AI assistant that truly understands and aligns with your organization’s unique development environment.
Ready to get started? Visit the Amazon Q Developer guide to learn more about setting up profiles and customizations for your organization. If you need help planning your customization strategy, contact your AWS account team or find an AWS Partner in the AWS Partner Network.
Los clientes de hoy esperan que las organizaciones satisfagan proactivamente sus necesidades con contenido personalizado, entregado en el momento, lugar y forma de su elección. Buscan interacciones dinámicas y conscientes del contexto con conversaciones sofisticadas a través de todos los canales de comunicación. Esta creciente demanda ejerce presión sobre las organizaciones para transformar sus flujos de trabajo de experiencia del cliente para mejorar la lealtad y aumentar la eficiencia operativa. Si bien los avances recientes en Generative AI (GenAI), incluida la hiperpersonalización y Agentic AI, ofrecen posibilidades interesantes, también presentan nuevos desafíos. Las organizaciones necesitan una arquitectura flexible y reutilizable que les permita incorporar GenAI en sus sistemas existentes de participación del cliente sin requerir una revisión completa de sus soluciones dispares actuales.
Esta publicación de blog explora cómo construir un centro de comunicaciones moderno impulsado por IA utilizando ejemplos de GitHub de código abierto que integran servicios de SMS/MMS y WhatsApp con capacidades de GenAI. Las organizaciones pueden crear experiencias innovadoras de cliente impulsadas por IA con una rápida prueba de concepto sin interrumpir los sistemas existentes.
En combinación con Vector Databases y Retrieval Augmented Generation (RAG), GenAI hace posible reorganizar el conocimiento en un solo sistema y consultar desde una única interfaz de usuario a través de conversación en lenguaje natural con un chatbot o asistente virtual. Canalizar las comunicaciones de los clientes a través de un centro de comunicaciones multicanal vinculado con capacidades de GenAI ayuda a unificar los mecanismos de participación del cliente y agiliza la creación de experiencias ricas para el cliente. Los clientes interactúan con agentes de IA y bots de preguntas y respuestas en el canal de comunicación que les resulta conveniente para autogestionar sus necesidades. Las organizaciones pueden construir experiencias de cliente agnósticas al canal de comunicación mientras recopilan eventos de participación del canal y datos conversacionales en un almacén de datos centralizado para obtener información en tiempo real, consultas ad-hoc, análisis y entrenamiento de ML.
Descripción general de la solución
En el núcleo de la solución se encuentra el Centro de Comunicaciones Moderno que conecta los canales de comunicación digital con servicios clave de GenAI, como Amazon Bedrock y Amazon Q, junto con servicios de AWS ML, bases de datos, almacenamiento y computación sin servidor.
AWS End User Messaging y Amazon SES proporcionan acceso a nivel de API a canales de comunicación digital, ofreciendo servicios seguros, escalables, de alto rendimiento y rentables para que las aplicaciones empresariales intercambien SMS/MMS, WhatsApp, notificaciones push y de voz, y correo electrónico con los clientes.
Una colección de código de muestra de código abierto, publicada en el repositorio AWS-samples de GitHub, ilustra cómo facilitar conversaciones generativas en canales SMS/MMS y WhatsApp. Esto se extenderá para incluir servicios de correo electrónico. Dos componentes clave forman la base de las Muestras de Integración de GenAI: el Orquestrador de chat Multicanal con Agentes de IA, y la Base de Datos de Participación y Análisis para End User Messaging y SES. Nos referiremos a estos simplemente como el Procesador de Conversaciones y la Base de Datos de Participación en el diagrama de la solución.
El Procesador de Conversaciones recibe mensajes de clientes a través de AWS End User Messaging y Amazon Simple Email Service (SES), almacena los detalles de la conversación e invoca al Agente de Amazon Bedrock relevante. Los Agentes de Amazon Bedrock utilizan Modelos de Lenguaje Grandes (LLMs) y bases de conocimiento para analizar tareas, dividirlas en pasos accionables, ejecutar esos pasos o buscar en la base de conocimiento, observar resultados y refinar iterativamente su enfoque hasta completar la tarea junto con una respuesta. Alternativamente, el Procesador de Conversaciones puede funcionar como un bot de preguntas y respuestas, en cuyo caso utiliza Amazon Bedrock Knowledge Bases junto con su función RAG para generar una respuesta LLM y enviarla por el mismo canal que el mensaje del cliente.
La Base de Datos de Participación recopila y combina datos de participación del cliente y registros conversacionales de todos los canales de comunicación, almacenando la información en un data lake centralizado en Amazon S3. Al convertir los datos a un formato común y canónico, la solución simplifica la consulta y el análisis de estos eventos entrantes. Una función Lambda Transformer aprovecha las Plantillas Apache Velocity para transformar los datos JSON entrantes, permitiendo obtener información en tiempo real.
Los datos de eventos sin procesar almacenados en el data lake de Amazon S3 pueden luego alimentar otros servicios de AWS para su procesamiento posterior. Por ejemplo, los datos pueden fluir hacia Amazon Connect Customer Data Profiles o Amazon SageMaker para apoyar el entrenamiento de modelos de machine learning. Los analistas de datos pueden usar Amazon Athena para realizar consultas directas para informes detallados ad-hoc, o enviar los datos a Amazon QuickSight para visualizaciones avanzadas y capacidades de consulta en lenguaje natural a través de Amazon Q en QuickSight.
Amazon Bedrock proporciona capacidades centrales de GenAI como LLMs, Knowledge Bases, Retrieval Augmented Generation (RAG), agentes de IA y Guardrails, para comprender las solicitudes de los clientes, determinar qué acción tomar y qué comunicar de vuelta. Amazon Bedrock Knowledge Bases proporciona conocimiento y razonamiento específico de la organización, mientras que los Agentes de Amazon Bedrock automatizan tareas de múltiples pasos conectándose perfectamente con los sistemas, APIs y fuentes de datos de la empresa.
Requisitos previos
Los siguientes requisitos previos son necesarios para construir su centro de comunicaciones moderno:
Una cuenta de AWS. Regístrese para obtener una cuenta de AWS en el sitio web de AWS si no tiene una.
Roles y permisos apropiados de AWS Identity and Access Management (IAM) para Amazon Bedrock, AWS End User Messaging y Amazon S3. Para más información, consulte Create a service role for model import.
Configuración de AWS End User Messaging: Necesitará configurar la identidad de origen necesaria en el servicio AWS End User Messaging para entregar mensajes a través de SMS o WhatsApp. Si configura SMS, se debe aprovisionar un Número de Teléfono de Origen SMS registrado y activo en AWS End User Messaging SMS. (Dentro de Estados Unidos, use 10DLC o Números Gratuitos (TFNs)). Si configura WhatsApp, se debe aprovisionar un número activo que haya sido registrado con Meta/WhatsApp en AWS End User Messaging Social.
Modelos de Amazon Bedrock: Bedrock Anthropic Claude 3.0 Sonnet y Titan Text Embeddings V2 habilitados en su región. Tenga en cuenta que estos son los modelos predeterminados utilizados por la solución; sin embargo, puede experimentar con diferentes modelos.
Docker instalado y en ejecución – Se utiliza localmente para empaquetar recursos para el despliegue.
Node (> v18) y NPM (> v8.19) instalados y configurados en su computadora
AWS CDK (v2) instalado y configurado en su computadora.
Implementación del Procesador de Conversaciones y Base de Datos de Participación
Implemente las siguientes dos soluciones. Si bien no es obligatorio, es mejor implementarlas en este orden, ya que las salidas de la Base de Datos de Participación pueden utilizarse en el ejemplo de Chat Multicanal:
Cada solución contiene instrucciones detalladas para implementar los servicios requeridos usando AWS Cloud Development Kit (CDK). La primera solución de Base de Datos de Participación creará un flujo de Amazon Data Firehose que puede utilizarse como entrada para la segunda aplicación de Chat Multicanal, de modo que los datos puedan almacenarse y consultarse en la Base de Datos de Participación.
Orquestrador de chat Multicanal con Agentes de IA
Esta solución demuestra cómo los usuarios pueden interactuar con tres diferentes fuentes de conocimiento. Puede que no necesite las tres, sin embargo, esto debería servir como un buen ejemplo para construir la fuente de conocimiento adecuada para su caso de uso particular:
Construya sus Bases de Conocimiento en Amazon Bedrock usando Amazon S3. Por defecto, la solución creará Bases de Conocimiento usando un Bucket de Amazon S3 como fuente de datos. Esta solución le permite cargar documentos a un bucket de Amazon S3 para poblar la base de conocimiento.
NOTA: El proyecto inicial crea un bucket S3 para almacenar los documentos utilizados para la Base de Conocimiento de Bedrock. Por favor, considere usar Amazon Macie para ayudar en el descubrimiento de datos potencialmente sensibles en buckets S3. Amazon Macie puede habilitarse en una prueba gratuita durante 30 días, hasta 150GB por cuenta.
Agentes de Amazon Bedrock: Opcionalmente permita que sus usuarios chateen con Agentes de Amazon Bedrock. Los agentes tienen el beneficio adicional de soportar bases de conocimiento para responder preguntas y guiar a los usuarios a través de la recopilación de información necesaria para automatizar una tarea como hacer una reserva. Hay agentes de ejemplo disponibles en el repositorio Amazon Bedrock Agent Samples. Tenga en cuenta que necesitará tener un Agente de Amazon Bedrock creado en su región antes de implementar la solución.
Conclusión
Un Centro de Comunicaciones Moderno, acoplado de manera flexible con servicios centrales de Generative AI, establecerá una base componible para construir experiencias de cliente agnósticas al canal de comunicación. Construya uno aprovechando las Muestras de Integración de GenAI, el Procesador de Conversaciones y la Base de Datos de Participación, combinándolos con los servicios de comunicación digital seguros, escalables, de alto rendimiento y rentables de AWS End User Messaging y Amazon SES. Esto proporcionará un único punto de acceso conversacional a bases de conocimiento y capacidades de IA agéntica en Amazon Bedrock. Comience a experimentar con innovaciones de experiencia del cliente impulsadas por IA con una rápida prueba de concepto que no interferirá con su configuración actual de participación del cliente.
Every Monday we tell you about the best releases and blogs that caught our attention last week.
Before continuing with this AWS Weekly Roundup, I’d like to share that last month I moved with my family to San Francisco, California, to start a new role as Developer Advocate/SDE, GenAI.
This excites me because I’ll have the opportunity to connect with new communities in the Bay Area while tackling exciting new challenges. If you’re part of a community focused on building generative AI and agentics applications, or know of one, I’d love to connect. Let’s connect!
Last week’s launches Here are the launches from last week:
New Amazon EC2 C8gn instances powered by AWS Graviton4 offering up to 600Gbps network bandwidth – Amazon Elastic Compute Cloud (Amazon EC2) C8gn instances are now generally available, powered by AWS Graviton4 processors and 6th generation AWS Nitro Cards. These network-optimized instances deliver up to 600 Gbps network bandwidth. This represents the highest bandwidth among EC2 network-optimized instances, with up to 192 vCPUs and 384 GiB memory. They provide 30% higher compute performance than C7gn instances and are ideal for network-intensive workloads like virtual appliances, data analytics, and cluster computing jobs.
Build the highest resilience apps with multi-Region strong consistency in Amazon DynamoDB global tables – Amazon DynamoDB global tables now supports multi-Region strong consistency (MRSC) for applications requiring zero Recovery Point Objective (RPO). This capability ensures applications can read the latest data from any Region during outages, addressing critical needs in payment processing and financial services. MRSC requires three AWS Regions configured as either three full replicas or two replicas plus a witness, providing the highest level of application resilience for mission-critical workloads.
Amazon Nova Canvas update: Virtual try-on and style options now available – Amazon Nova Canvas introduces virtual try-on capabilities that help you visualize how clothing looks on a person by combining two images, plus eight new pre-trained style options (3D animation, design sketch, vector illustration, graphic novel, etc.) for generating images with improved artistic consistency. Available in three AWS Regions, these features enhance AI-powered image generation capabilities for retailers and content creators seeking realistic product visualizations.
Amazon Q in Connect now supports 7 languages for proactive recommendations – Amazon Q in Connect, a generative AI-powered assistant for customer service, now provides proactive recommendations in seven languages: English, Spanish, French, Portuguese, Mandarin, Japanese, and Korean. The AI-powered customer service assistant detects customer intent during voice and chat interactions to help agents resolve issues quickly and accurately.
Amazon Aurora DSQL is now available in additional AWS Regions – Amazon Aurora DSQL expands to Asia Pacific (Seoul) and now supports multi-Region clusters across Asia Pacific and European regions. This serverless, distributed SQL database offers unlimited scalability, highest availability, and zero infrastructure management with AWS Free Tier access.
Other AWS blog posts
Optimize RAG in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service – Learn how to optimize Retrieval Augmented Generation (RAG) in production environments using Amazon SageMaker JumpStart and Amazon OpenSearch Service. This comprehensive guide demonstrates implementing RAG workflows with LangChain, covers OpenSearch optimization strategies, provides setup instructions, and explains benefits of combining these AWS services for scalable, cost-effective generative AI applications.v
Agentic GenAI App Using Bedrock, MCP servers on EKS – This post shows how to build a scalable AI chat application using Amazon Bedrock, Strands Agent, and Model Context Protocol (MCP) servers deployed on Amazon Elastic Kubernetes Service (Amazon EKS). The architecture combines agentic workflows with containerized microservices for intelligent, auto-scaling conversations with multiple foundation models.
Enforce table level access control on data lake tables using AWS Glue 5.0 with AWS Lake Formation – AWS Glue 5.0 introduces Full-Table Access (FTA) control for Apache Spark with AWS Lake Formation, providing table-level security without fine-grained access overhead. This feature supports native Spark SQL/DataFrames for Lake Formation tables. It enables read/write operations on Iceberg and Hive tables with improved performance and lower costs.
Upcoming AWS events Check your calendars and sign up for these upcoming AWS events:
AWS re:Invent – Register now to get a head start on choosing your best learning path, booking travel and accommodations, and bringing your team to learn, connect, and have fun. Early-career professionals can apply for the All Builders Welcome Grant program, designed to remove financial barriers and create diverse pathways into cloud technology. Applications are now open and close on July 15, 2025.
AWS NY Summit – You can gain insights from Swami’s keynote featuring the latest cutting-edge AWS technologies in compute, storage, and generative AI. My News Blog team is also preparing some exciting news for you. If you’re unable to attend in person, you can still participate by registering for the global live stream. Also, save the date for these upcoming Summits in July and August near your city.
AWS Builders Online Series – If you’re based in one of the Asia Pacific time zones, join and learn fundamental AWS concepts, architectural best practices, and hands-on demonstrations to help you build, migrate, and deploy your workloads on AWS.
Join AWS Gen AI Lofts – Experience AWS Gen AI Lofts across San Francisco, Berlin, Dubai, Dublin, Bengaluru, Manchester, Paris, Tel Aviv, and additional locations – hands-on workshops, expert guidance, investor networking, and collaborative spaces designed to accelerate your generative AI startup journey.
Amazon Q Developer is the most capable generative AI–powered assistant for software development, helping developers perform complex workflows. Amazon Q Developer command-line interface (CLI) combines conversational AI with direct access to AWS services, helping you understand, build, and operate applications more effectively. The Amazon Q Developer CLI executes commands, analyzes outputs, and provides contextual recommendations based on best practices for troubleshooting tools and platforms available on your local machine.
In today’s cloud-native environments, troubleshooting production issues often involves juggling multiple terminal windows, parsing through extensive log files, and navigating numerous AWS console pages. This constant context-switching delays problem resolution and adds cognitive burden to teams managing cloud infrastructure.
In this blog post, you will explore how Amazon Q Developer CLI transforms the troubleshooting experience by streamlining challenging scenarios through conversational interactions.
The Traditional Troubleshooting Experience
When issues arise, engineers typically spend hours manually examining infrastructure configurations, reviewing logs across services, and analyzing error patterns. The process requires switching between multiple interfaces, correlating information from various sources, and deep AWS knowledge. This complex workflow often extends problem resolution from hours into days and increase the burden on the infrastructure teams.
Solution: Amazon Q Developer CLI
Amazon Q Developer CLI streamlines the entire troubleshooting process, from initial investigation to problem resolution, making complex AWS troubleshooting accessible and efficient through simple conversations.
How Amazon Q Developer CLI works:
Natural Language Interface: Execute AWS CLI commands and interact with AWS services using conversational prompts
Automated Discovery: Map out infrastructure and analyze configurations
Intelligent Log Analysis: Parse, correlate, and analyze logs across services
Root Cause Identification: Pinpoint issues through AI-powered reasoning
Guided Remediation: Implement fixes with minimal human intervention
Validation: Test solutions and explain complex issues simply
One of the built-in tools within the Amazon Q Developer CLI, use_aws, enables natural language interaction with AWS services, as shown in Figure 1. This tool leverages the AWS CLI permissions configured on your local machine, allowing secure and authorized access to your AWS resources.
Figure 1: Tools selection in Amazon Q Developer CLI
Real-World Troubleshooting Scenario
Demonstration Environment Setup
This demonstration was performed with the following environment configuration:
Application and infrastructure code available locally
The environment includes a local development machine with necessary tools, appropriate AWS account permissions, and terminal access. By starting Amazon Q Developer CLI in the project directory, it has immediate access to relevant code and configuration files.
Scenario: Troubleshooting NGINX 5XX Errors
The scenario demonstrates troubleshooting a multi-tier application architecture as shown in figure 2 deployed on Amazon ECS Fargate with:
Application Load Balancer (ALB) distributing traffic across availability zones
NGINX reverse proxy service handling incoming requests
Node.js backend service processing business logic
Service discovery enabling internal communication
CloudWatch Logs providing centralized logging
Figure 2: AWS Architecture diagram for the app used in this blog post
Traditional Troubleshooting Steps
For the architecture in figure 2, when 502 Gateway Timeout errors occur, traditional troubleshooting requires:
Checking ALB target group health
Examining ECS service status across multiple consoles
Analyzing CloudWatch logs from different log groups
Correlating error patterns between services
Reviewing infrastructure code for configuration issues
Implementing and deploying fixes
Amazon Q Developer CLI Approach
Instead, let’s see how Amazon Q Developer CLI handles this systematically, step by step:
Step1: Initial Problem Report
Amazon Q Developer CLI is provided with the initial prompt as a problem statement within the application project directory as shown in the following screenshot in figure 3. Amazon Q Developer responds back and says it is going investigate the 502 Gateway Timeout errors in the NGINX application.
Prompt:
Our production NGINX application is experiencing 502 Gateway Timeout errors.
I have checked out the application and infrastructure code locally and the AWS CLI
profile 'demo-profile' is configured with access to the AWS account where the
infrastructure and application is deployed to. Can you help investigate and diagnose the issue?
Figure 3: Amazon Q Developer CLI with initial prompt and problem statement
Step2: Systematic Infrastructure Discovery
Amazon Q Developer CLI start to systematically discovering the infrastructure as shown in the following screenshot in figure 4. If you see the initial prompt did not include that the app is hosted on ECS, but Amazon Q Developer CLI understood the context and executes the AWS CLI calls to describe the Cluster and the services within it. It made sure that the ECS tasks are running for both the services within the Cluster. It is a key discovery that both services show healthy status (1/1 desired count), indicating the issue isn’t service availability.
Figure 4: AWS Infrastructure discovery by Amazon Q Developer CLI
Step 3: Intelligent Log Analysis
Amazon Q Developer CLI retrieves and analyzes recent CloudWatch logs from the NGINX container, immediately identifying the critical error pattern as shown in the following screenshot in figure 5, where Amazon Q Developer responds: “Perfect! I found the issue. The NGINX logs show clear 504 gateway timeout with upstream timeout messages.”
Figure 5: CloudWatch Log analysis by Amazon Q Developer CLI
Step 4: Amazon Q Developer CLI Analysis and Root Cause Identification
Amazon Q Developer examines backend service logs and discovers a mismatch between the backend service response time and NGINX timeout settings, as seen in the following screenshot in figure 6.
Figure 6: Root cause identification by Amazon Q Developer CLI
Step 5: Amazon Q Developer CLI Root Cause Analysis
Amazon Q Developer CLI examines the ECS task definitions to identify the exact configuration mismatch, as shown in the following screenshot in figure 7. Amazon Q Developer finds that:
Backend service is configured with response_delay=15000 (15 secs)
NGINX proxy is configured with proxy_read_timeout 10s
This mismatch causes 504 gateway timeout errors when the backend response exceeds NGINX’s timeout threshold.
Figure 7: Root cause analysis and issue detection by Amazon Q Developer CLI
Step 6: Automated Code Fix
Here’s where Amazon Q Developer CLI truly excels—it doesn’t just diagnose; it implements the fix. Since Amazon Q Developer CLI is started within the project where the CDK code for ECS task definition is defined, it identified the code configuration and also modified it, as shown in the following screenshot in figure 8.
Figure 8: CDK code fix by Amazon Q Developer CLI
Step 7: Deployment
Amazon Q Developer CLI builds and deploys the fix by executing cdk synth and cdk deploy using the ‘demo-profile‘ AWS CLI profile that was initially provided in the prompt, as shown in the following screenshot in figure 9.
Figure 9: CDK code build and deployment by Amazon Q Developer CLI
Step 8: Validation
Amazon Q Developer CLI validates the solution by sending a curl request to the ALB endpoint after the successful deployment, as shown in the following screenshot in figure 10.
Figure 10: Fix validation by Amazon Q Developer CLI
In addition to that, Amazon Q Developer also sends a request to the health check endpoint and validates everything is working after the fix was deployed, as shown in the following screenshot in figure 11.
Figure 11: Health endpoint validation by Amazon Q Developer CLI
What Amazon Q Developer CLI Accomplished
Using just conversational commands, Amazon Q Developer CLI performed a complete troubleshooting cycle:
Infrastructure Discovery: Automatically mapped ECS clusters, services, and dependencies
Log Correlation: Analyzed thousands of log entries across multiple services
Root Cause Analysis: Identified exact configuration mismatch between NGINX’s timeout (10s) and the backend’s response delay (15s)
Code-Level Diagnosis: Located problematic timeout setting in CDK infrastructure code
Automated Implementation: Modified infrastructure code to increase the NGINX timeout
End-to-End Deployment: Built, deployed, and validated the complete solution
Comprehensive Testing: Verified both fix effectiveness and overall system health
Amazon Q Developer CLI handles troubleshooting tasks through a single, conversational interface, eliminating the need for multiple tools or AWS CLI commands.
Conclusion
Amazon Q Developer CLI represents a significant evolution in how we troubleshoot cloud infrastructure issues. By combining natural language understanding with powerful command execution capabilities, it transforms complex troubleshooting workflows into efficient, action-oriented dialogues. Whether you’re dealing with NGINX 5XX errors or similar issues across other AWS services, Amazon Q Developer CLI can help you diagnose issues, implement fixes, and validate solutions—all through a conversational interface that feels natural and intuitive.
Give Amazon Q Developer CLI a try the next time you encounter a troubleshooting challenge, and experience the difference it can make in your operational workflow.
Kirankumar Chandrashekar is a Generative AI Specialist Solutions Architect at AWS, focusing on Amazon Q Developer. Bringing deep expertise in AWS cloud services, DevOps, modernization, and infrastructure as code, he helps customers accelerate their development cycles and elevate developer productivity through innovative AI-powered solutions. By leveraging Amazon Q Developer, he enables teams to build applications faster, automate routine tasks, and streamline development workflows. Kirankumar is dedicated to enhancing developer efficiency while solving complex customer challenges, and enjoys music, cooking, and traveling.
Customers adopting Amazon Q Developer, a generative AI-powered coding companion, often need authentication through existing identity providers like PingIdentity. By leveraging AWS IAM Identity Center, organizations can enable their developers to access Amazon Q Developer with their existing PingIdentity credentials, streamlining authentication and removing the need for separate login procedures. Amazon Q Developer can chat about code, provide inline code completions, and generate new code. It also scans your code for security vulnerabilities and makes code improvements, including language updates, debugging, and optimizations. Amazon Q Developer comes in two tiers. The Free Tier is available at no cost for individual use. The Pro Tier is a paid version offering enterprise access controls, an analytics dashboard, customization, and higher usage limits. Organizations that enable the Pro tier of Amazon Q Developer for their developers typically authenticate with AWS IAM Identity Center. This approach is popular due to its ability to federate with external identity providers. In this blog, we will show you how to set up PingIdentity as an external IdP for IAM Identity Center and allow developers to access Amazon Q Developer using their existing PingIdentity login credentials.
How it works
Figure 1 – Solution Overview
The authentication workflow is as follows:
The developer initiates an access request to Amazon Q Developer.
IAM Identity center checks authentication status.
If not authenticated, redirects to PingIdentity login.
Developer provides PingIdentity Credentials.
PingIdentity validates credentials and sends SAML response.
IAM Identity Center verifies the SAML response.
Upon successful verification, grants Amazon Q Developer access.
Developer begins using Amazon Q Developer.
Prerequisites
AWS account
PingIdentity environment with users and groups already setup for Amazon Q Developer access
IAM identity center
Pro Tier subscription of Amazon Q Developer
Walkthrough
In this section, we demonstrate how to create a SAML-based connection between PingIdentity and IAM Identity Center, enabling you to access Amazon Q Developer seamlessly using your PingIdentity credentials.
Note: You will need to switch between PingIdentity portal and IAM Identity Center in your browser. We recommend opening a new browser tab for each console.
Step 1: Enable AWS Single Sign-On in PingIdentity
This step involves enabling AWS Single Sign-On application within PingIdentity.
In the PingIdentity console, Navigate to the Applications Tab > Application Catalog
Browse catalog for AWS Single Sign-On and select + to start the Quick Setup.
Figure 2 – PingIdentity Application Catalog
Alt Text: Screenshot of the PingIdentity Application Catalog interface. The search term “aws” is entered in the search bar, displaying three results: Amazon Web Services – AWS, AWS Gov-Cloud, and AWS Single Sign-On. The “AWS Single Sign-On” option is outlined with a red box and includes a plus button to add the application
Provide Name, SSO Region and SSO Tenant ID and choose Next
Name – Input an appropriate name for the connection
SSO Region – Input the appropriate region
Tenant ID – Identity Store ID You can run the following CLI command to retrieve the value. It’s a 10-digit alphanumeric prefixed by “d-“.
Navigate to PingOne Mappings and select Email Address from the drop down.
Figure 3 – AWS Single Sign-On attribute mapping
Alt Text: Screenshot of the AWS Single Sign-On configuration in PingIdentity. The screen shows Step 2 of the setup process where the SAML attribute SAML_SUBJECT is mapped to the PingOne attribute “Email Address”. A red box highlights the mapping section under “PingOne Mappings”.
Search and select the group that you have created earlier for enabling access to Amazon Q Developer and select + to add the group.
Choose Save
Figure 4 – Select PingIdentity directory Groups for Amazon Q Developer access
Alt Text: Screenshot of Step 3 in the AWS Single Sign-On setup process in PingIdentity. The screen shows the group selection interface where the “Amazon Q” group is listed. A plus icon is shown next to the group to add it, and a blue “Save” button is highlighted in the bottom-right corner to confirm the configuration.
Step 2: Connecting PingIdentity with IAM identity Center
This step involves configuring PingIdentity with the AWS IAM Identity Center sign-on details to complete the authentication setup.
In the PingIdentity console, Navigate to the Applications Tab > Applications and select the application you created earlier in Step 1
Select Enable Advanced Configuration and choose Enable.
Figure 5 – Enable Advanced configuration for AWS single Sign-On application
Alt Text: Screenshot of the PingIdentity Applications dashboard showing the AWS Single Sign-On application selected. The overview panel displays key configuration sections including protocol (SAML), mapped attributes, selected policies, and access group (Amazon Q). The option “Enable Advanced Configuration” is highlighted near the bottom of the panel.
Scroll down and select Download Metadata. This will save the Metadata file to your local computer, which you will use later during the configuration process.
Under Identity source, select Change identity source from the Actions drop-down menu.
Figure 6 – Change identity source in IAM Identity Center Console
Alt Text: Screenshot of the IAM Identity Center settings page, focused on the “Identity source” tab. The page displays details such as identity source, authentication method, AWS access portal URL, issuer URL, and identity store ID. A dropdown menu labeled “Actions” is expanded in the top-right corner, showing options to “Customize AWS access portal URL” and “Change identity source,” highlighted with a red box.
On the next page, select External identity provider and choose Next.
Under Service provider metadata copy the IAM Identity Center Assertion Consumer Service (ACS) URL.
Figure 7 – Copy IAM Identity Center ACS URL
Alt Text: Screenshot of the “Configure external identity provider” step in the AWS IAM Identity Center setup process. The screen displays service provider metadata including the AWS access portal sign-in URL, IAM Identity Center Assertion Consumer Service (ACS) URL (highlighted with a red box), and IAM Identity Center issuer URL. A button labeled “Download metadata file” is shown in the upper right.
Now go back to the PingIdentity browser tab and Navigate to the Configuration tab and select pencil icon to edit the details.
Paste the ACS URL you copied from the IAM identity center console and choose Save.
Figure 8 – Configuring AWS Single Sign-On SAML Settings in PingIdentity console
Alt Text: Two screenshots showing the configuration and editing of SAML settings for AWS Single Sign-On in PingIdentity. The first image displays the static configuration view, listing the ACS URL, signing key (“PingOne SSO Certificate for Administrators environment”), signing method (“Response”), and signing algorithm. The second image shows the editable configuration screen with the ACS URL input field highlighted in red, alongside dropdowns for selecting the signing key, options for signing method (Assertion, Response, or both), and the RSA_SHA256 signing algorithm. These screens guide users through setting up secure SAML integration with AWS SSO.
Step 3: Configure PingIdentity as external IdP in IAM identity Center
This step involves setting up PingIdentity as an external IdP in IAM Identity Center to enable federated access.
Navigate back to the previous browser tab where you had IAM Identity Center console open.
Upload the downloaded PingIdentity IdP SAML metadata file from step 3 of previous section and select Next.
Figure 9 – AWS IAM Identity Center metadata
Alt Text: Screenshot of the AWS Identity Center configuration screen where the user uploads the IdP SAML metadata XML file. The metadata file is shown as successfully selected. Below are empty fields for optional manual entry of IdP sign-in URL, IdP issuer URL, and IdP certificate. The “Next” button is highlighted in orange at the bottom right, indicating the next step in the setup process.
Review the list of changes. Once you are ready to proceed, type ACCEPT, then select Change identity source.
Step 4: Enable provisioning and identity-aware sessions in IAM identity Center
This step involves configuring user provisioning and enabling identity-aware sessions in AWS IAM Identity Center to support dynamic access control.
On the Settings page, locate and enable automatic provisioning. This immediately enabled automatic provisioning in IAM Identity Center and displays the necessary SCIM endpoint and access token information.
In the Inbound automatic provisioning dialog box, copy each of the values for the following options. You will need to paste these later when you configure provisioning in PingIdentity.
Figure 10 – IAM Identity Center Settings for identity aware sessions and automatic provisioning
Alt Text: Two options are displayed for further configuration: “Enable identity-aware sessions” and “Automatic provisioning.” Both options have an “Enable” button on the right-hand side, highlighted in red.
Step 5: Configure connections provisioning in PingIdentity
This step involves setting up connection provisioning in PingIdentity to enable automatic user and group management.
In the PingIdentity console, Navigate to the Integrations > Provisioning.
Select plus icon > New Connection
Under connection type Select Identity Store.
Figure 11 – PingIdentity connection provisioning
Alt Text: PingIdentity Provisioning configuration screen. The left sidebar highlights the “Provisioning” tab. The main panel shows the “Create a New Connection” dialog with two connection type options: “Identity Store” and “Gateway.” The “Identity Store” option is selected using the “Select” button on the right. A plus (+) icon at the top indicates the option to add a new provisioning connection.
Select SCIM outbound from the list of options and select Next.
Provide a name for the connection and select Next.
Paste the SCIM endpoint URL into the SCIM BASE URL field.
Navigate to Authentication Method and select OAuth 2 Bearer Token.
Paste the Access token into the Oauth Access Token field.
Select Test Connection to validate the connectivity and select Next.
Figure 12 – Configure authentication details
Alt Text: PingIdentity interface showing the “Configure Authentication” step in the “Create a New Connection” wizard. Key fields include the SCIM Base URL, SCIM Version (2.0), Authentication Method (OAuth 2 Bearer Token), OAuth Access Token (obscured), and resource paths for Users and Groups. The “Test Connection” and “Next” buttons are visible at the bottom.
Navigate to User Filter Expression and change to userName Eq “%s”.
Choose Save. By default, the connection is created in a Disabled state.
Figure 13 – Edit UserFilter Expressions for the connection
Alt Text: Final step in the PingIdentity “Create a New Connection” wizard showing the “Configure Preferences” screen. The highlighted fields include “User Filter Expression” with the value userName Eq “%s”, “User Identifier” set to userName, and group membership handling options (“Merge” and “Overwrite” with “Overwrite” selected). A “Save” button is highlighted at the bottom right.
Select the connection you created and select the toggle switch to enable the connection.
Figure 14 – Enable the connection
Alt Text: PingIdentity configuration screen showing the IAM Identity Store integration. The page displays the identity store name, and tabs for “Overview” and “Configuration.” A toggle switch in the top-right corner is highlighted, indicating the integration is currently enabled.
Step 6: Configure rules provisioning in PingIdentity
This step involves setting up provisioning rules in PingIdentity to define how users and groups are synchronized.
In the PingIdentity console, Navigate to the Integrations > Provisioning.
Select plus icon > New Rule
Provide a Name and Description for the rule.
Choose Create.
Select plus icon to select the Connection you created in the previous step.
Choose Save.
Figure 15 – Add the IAM identity center connection to the rule
Alt Text: Screenshots showing the final steps in connecting the IAM Identity Center to the IAM identity store using PingIdentity. The first image shows the IAM Identity Store connection listed under “Available Connections” with a plus (+) icon to initiate the link. The second image shows the selected connection from the PingOne Directory (P1) as the source and IAM identity store (SCIM) as the target, with the option to “Save” the configuration.
If you want to sync users from your PingIdentity directory, create a user filter. To do so, navigate to User Filter and select pencil icon to edit the settings.
Choose the appropriate filter from the drop down based on your use case and select Save. I have chosen Group Name which has been designated for Amazon Q Developer access.
Figure 16 – PingIdentity user filter
Alt Text: Screenshot of the “Edit User Filter” interface in IAM Identity Center. The user filter is configured to provision users who belong to a group with names that contain “Amazon Q Developer.” The condition logic is set to match if “Any” of the conditions are true.
If you want to sync a group from your PingIdentity directory, create group provisioning. To do so, navigate to Group Provisioning and select pencil icon to edit the settings.
Select the appropriate group which has been designated for Amazon Q Developer access and choose Save.
Figure 17 – PingIdentity Group Provisioning
Alt Text: Screenshot of the “Edit Group Provisioning” screen in IAM Identity Center. The group “Amazon Q Developer” is selected for outbound provisioning. A “Save” button is highlighted in the bottom-left corner.
Navigate to Attribute Mapping and select the pencil icon to edit the settings.
Delete the PingOne Directory attribute Primary Phone.
Add a new attribute and select Username as PingOne Directory and displayName as IAM identity Store.
Choose Save.
Figure 18 – PingIdentity attribute mapping
Alt Text: Two screenshots showing the editing of attribute mappings in IAM Identity Center. The first image displays default mappings such as ‘Email Address’ to ‘workEmail’ and ‘Username’ to ‘userName’, with an option to delete or update each field. The second image shows the addition of a new attribute mapping from ‘Username’ to ‘displayName’, along with highlighted ‘Add’ and ‘Save’ buttons.
Select the rule you created and select the toggle switch to enable the rule.
This automatically provisions the users/groups from PingIdentity to IAM identity Center using SCIM.
Figure 19 – PingIdentity Users and Groups Sync status using SCIM
Alt Text: IAM Identity Center sync summary showing successful user and group provisioning. The first image highlights two users impacted and successfully synced. The second image highlights one group impacted and successfully synced. Sync status is marked ‘ACTIVE’ in both views, confirming successful integration between PingOne and AWS IAM Identity Center.
Step 7: Provide access to Amazon Q Developer
This step involves locating and subscribing the groups that need permission to use Amazon Q Developer.
In the Amazon Q Developer console, under Subscriptions add the IAM identity center groups which require access to Amazon Q Developer.
Select Subscribe and search for the group name.
Select Assign.
Figure 20 – Amazon Q Developer subscriptions page
Alt Text: Screenshot of the Amazon Q Developer Subscriptions page in the AWS Management Console. The “Groups” tab is selected, displaying “Amazon Q Developer,” with a subscription status of “Subscribed.” The “Amazon Q Developer” group is highlighted with a red box.
Setup Amazon Q Developer with IAM Identity Center
This section guides you through installing the Amazon Q Developer extension and setting up authentication with IAM Identity Center.
To set up Amazon Q Developer extension in your integrated development environment (IDE), complete the steps in AWS documentation.
Once extension is installed Choose Amazon Q icon in your IDE.
Choose a sign-in option.
Select Use with Pro license and choose
Continue.
Provide the Start URL. You can retrieve this AWS access portal URL from the IAM Identity Center Console.
Figure 21 – IAM identity center access portal URL
Alt Text: Screenshot of the IAM Identity Center settings page in the AWS Console, displaying the identity source configuration. It shows that the identity source is set to “External identity provider” with SAML 2.0 authentication and SCIM provisioning. The highlighted section includes the AWS access portal URL and the Identity Store ID. The “Settings” tab is selected in the left navigation pane.
Provide the region that hosts the identity directory and choose Continue
Select Open on the resulting pop up which redirects to your browser.
The browser redirects you to the Pingone URL where you enter your PingIdentity credentials and select Sign On.
Upon successful authentication, select Allow access on the resulting pop up to login successfully.
Alt Text: A screen recording of Visual Studio Code where the user selects the Amazon Q icon from the sidebar. The screen transitions to a login prompt indicating that the user must authenticate using their PingIdentity credentials via IAM Identity Center before accessing Amazon Q Developer features. The message highlights that authentication is required to continue.
Test Configuration
Upon successfully completing the previous step, you can now leverage the code suggestions by Amazon Q Developer.
Figure 23 – Amazon Q Developer example
Alt Text: A screen recording of Visual Studio Code where Amazon Q Developer generates a sample code inline.
Clean Up
To avoid ongoing charges after testing this solution, follow these steps to remove all provisioned resources:1. Remove PingIdentity Application Configuration
In the PingIdentity console, navigate to Applications.
Locate and delete the AWS Single Sign-On application that was configured for IAM Identity Center integration.
2. Reset IAM Identity Center Configuration
In the AWS IAM Identity Center console:
Navigate to Settings > Identity source.
Change the identity source back to the default IAM Identity Center directory if no longer using PingIdentity.
Remove any external metadata and configuration uploaded during the setup.
3. Revoke Subscriptions and Access
In the Amazon Q Developer console:
Go to Subscriptions and remove assigned groups such as Amazon Q Developer or code whisperer trial.
This will deactivate access and prevent any future charges tied to those subscriptions.
4. Remove Amazon Q Developer Extension
If desired, uninstall the Amazon Q Developer extension from Visual Studio Code to fully revert the development environment.
Conclusion
In this post, we demonstrated how to use existing PingIdentity credentials to access Amazon Q Developer through integration with IAM Identity Center. We provided a step-by-step guide for configuring PingIdentity as an external identity provider (IdP) with IAM Identity Center. Lastly, we demonstrated how to connect Amazon Q Developer extension within your IDE to AWS using your PingIdentity credentials, allowing seamless access to Amazon Q Developer.If you have any comments or questions, share them in the comments section.
Sid Vantair is a Solutions Architect with AWS covering Strategic accounts. He thrives on resolving complex technical issues to overcome customer hurdles. Outside of work, he cherishes spending time with his family and fostering inquisitiveness in his children.
Earlier today, Amazon Q Developer announced Model Context Protocol (MCP) support in their Integrated Development Environment (IDE) plugins for Visual Studio Code and JetBrains. This allows developers to connect external tools or MCP servers to Q Developer, enabling more context-aware responses and complex workflows. MCP support has already been available in Amazon Q Developer for Command Line since April 29, 2025.
Introduction
Q Developer already had the ability to use tools within the IDE such as executing shell commands, reading local files, and generating code with the addition of the agentic coding experience. Now, developers have the ability to add additional tools that support MCP to their toolkit. MCP is an open protocol that standardizes how Large Language Models (LLMs) integrate with applications. It provides a way to share context, access data sources, and interact with APIs. You can read more about MCP in this introduction.
This ability to add additional context and tools allows Q Developer to write more accurate code, integrate with your planning tools, create UI components from designs, generate database documentation by examining your actual schema, and execute complex multi-tool tasks – all without the need for custom integration code. I’m excited to see this functionality coming to Q Developer IDE plugins, enhancing the development process right where developers spend most of their time.
In this post, I’ll walk you through a common scenario where I, as a developer, am tasked with working on an issue defined in a project management tool like Jira. The issue contains a user story, acceptance criteria, a link to a Figma design of the user interface, and additional technical implementation notes. To accomplish this efficiently, I’ll demonstrate how Q Developer can streamline the entire process by using two separate MCP servers to interact with Jira and Figma independently. Rather than manually switching between browser tabs, copying information, and trying to keep track of requirements across multiple tools, I’ll show how Q Developer can automatically fetch details using MCP and help me implement the feature while maintaining context across both platforms as shown in the figure below.
Figure 1: Q Developer extension in Visual Studio Code interacting with external tools using MCP servers
Configuring MCP Servers
To begin setup, click on the ConfigureMCP servers button at the top of the Chat tab bar as shown in the image below. This will bring up the list of MCP servers currently configured. Click the + (Add new MCP) button to add a new server.
Figure 2: Add MCP server configuration in Visual Studio Code’s Q Developer extension
You will set the scope of your MCP servers during configuration. A Global scope allows you to use the MCP server across all your projects, whereas a Workspace scope sets it up for only the current IDE workspace. Here’s an example configuration for the Atlassian and Figma MCPs I’ll be using:
Note: The first time you set up the Atlassian MCP server, you’ll be asked to complete the OAuth authentication flow in your browser and provide access permissions to your Jira projects. Similarly, to connect to the Figma Dev Mode MCP server, you’ll need to enable it via the Figma desktop app.
To understand an MCP server’s individual tools, click on the expand icon next to its name as shown in the image below. Tools are executable functions exposed by the MCP server. They enable Q Developer’s agentic chat to perform actions and interact with external systems on your behalf. You can also configure permissions for individual tools. Each tool presents the option to Ask, Always allow, or Deny it such that Q Developer can’t invoke it. In my example, I’ll set all tools that only read data to Always allow for my workspace and set the rest of the tools to Ask.
Figure 4: MCP tool descriptions and configuration dropdown with options to Ask, Always allow or Deny
With the MCP servers configured, let’s see how I can integrate them into my workflow.
Walkthrough
Q Developer is now enriched with additional information and tools available via the configured MCP servers. To demonstrate how this accelerates my developer productivity, I’ll be working with the Q Words game.
Scenario
Q-Words is an interactive word guessing game used in our customers’ workshops to demonstrate Q Developer’s capabilities. I’ve been tasked by the Product Manager to add a dark mode to the game. The User Story is logged in Jira and links to a Figma design that our designers have prepared.
Figure 5: Jira ticket showing user story and acceptance criteria for adding dark mode to a Q-Words game application
Figure 6: Figma design showing dark and light mode interfaces for a QWords game application
Integrating MCPs into your development workflow
Let’s begin by asking Q Developer to check on tasks assigned to me in Jira by typing the following prompt in the agentic chat:
List issues that I need to work on
Q Developer will understand your intent and interact with your Atlassian MCP server to filter and show Jira issues that are assigned to you and in the To Do state. You can optionally prompt Q Developer to use a particular MCP server. Just as with any prompt, providing clear instructions will yield better results. In the image below, Q Developer retrieves details for the issue I’m assigned to work on.
Figure 7: Q Developer retrieves and describes issues assigned to me in Jira using the Atlassian MCP server
Let’s begin work on the issue with the following prompt:
Move issue CRM-9 to In Progress and checkout a new git branch named after the issue id to begin working on it
Figure 8: Prompt Q Developer to begin working on an assigned issue
Next, I’d like to understand the impact of the design changes on the current application. I can use the following prompt to accomplish this:
Analyze the Jira User Story and linked Figma design. Give me a technical implementation plan explaining the UI components that will need to be modified in the existing code.
Figure 9: Prompt Q Developer to help you analyze changes in existing code to implement the new UI
Q Developer automatically pulls in issue details from Jira, along with the design specifics like colors from Figma. Before MCP, I would have had to add those details directly into the prompt or provided them as context from a local file. Now, my prompt only includes the description of the task whereas the context is enriched with details from the MCP servers. Review the proposed plan and suggest edits if needed. Once satisfied, prompt Q Developer to begin working on the changes:
Implement the plan
Figure 10: The diff view of changes by Q Developer to implement a dark mode feature in HTML and CSS
After reviewing the diff of the files changed by Q Developer, I can verify that the new Dark Mode feature has been implemented as desired. Let’s test the changes and ensure all acceptance criteria is met. To run the application, I use the following prompt:
Run the application locally
Q Developer will ask permission and run commands to spin up the local web server. I can then test the changes in my browser.
Figure 11: Updated application with dark mode toggle button implemented by Q Developer using MCP
After a bit of testing, I can confirm that we’ve met all the acceptance criteria for the story. Let’s update the rest of the team on what we’ve accomplished with the following prompt:
Update the Jira issue status to Done and add a comment summarizing the changes made.
This convenient integration between Q Developer and Jira via MCP, saves me the back and forth between different tools to document the work accomplished.
Figure 12: A Jira ticket comment detailing the completed implementation of dark mode features, including theme toggle, CSS variables, and UI components
Conclusion
The addition of MCP support in Amazon Q Developer for the IDE provides a standardized way to share context and interact with additional tools. In this post, I’ve demonstrated how I can use Q Developer in the IDE to interact with Atlassian Jira for task management and Figma for UI updates. I was able to do this without explicitly including user story details in my prompts or separately downloading design assets from UI mockups. Instead, Q Developer could automatically access user story context and easily integrate design assets using tools exposed by MCP servers. I encourage you to explore the new MCP capabilities and also check out the AWS MCP Servers repository on GitHub. Refer MCP configuration for Q Developer in the IDE to learn more.
Amazon Q Developer now supports Claude Sonnet 4 within the CLI, bringing advanced coding and reasoning capabilities to your development workflows at no additional cost. This latest model excels in coding with a state-of-the-art 72.7% for agentic coding on the SWE-bench (see Claude 4 announcement for more information). With enhanced coding and reasoning capabilities, it helps you analyze complex code, optimize everyday development tasks, implementing bug fixes, running bash commands, and developing new features with immediate feedback loops and more precise responses.
To help you leverage Claude Sonnet 4, Amazon Q Developer lets you easily select specific Claude Sonnet models, giving you increased flexibility the CLI.
Claude Sonnet 4: High-performance model with balanced intelligence
Claude Sonnet 3.7: High-performance model with extended thinking capability
Claude Sonnet 3.5: High-performance intelligent model
For detailed information about Claude model capabilities and comparison, refer to the Anthropic models overview.
In this blog, I will show you how to select Claude Sonnet 4 as your model within the Q Developer CLI and then walk you through a quick demo.
How to Choose Claude Sonnet 4
Make sure to update to the latest version (v1.11.0 onwards) of Amazon Q Developer CLI. Refer installing Amazon Q for command line for installation instructions. You can access Claude Sonnet 4 through these options:
During an active chat, use the /model command and select claude-4-sonnet
Start a new chat with q chat --model claude-4-sonnet
Set it as your default model using q settings chat.defaultModel claude-4-sonnet.
The supported model names for the --model parameter and settings are:
claude-3.5-sonnet
claude-3.7-sonnet (default)
claude-4-sonnet
Model Selection Priority Order
Q Developer CLI selects models in the following order:
Current session model selections (via /model or --model)
User-configured preferences in settings
System default (Claude 3.7 Sonnet)
Key Behaviors
The Q Developer CLI agent defaults to Claude 3.7 Sonnet when no specific model is selected. During active chat sessions, you can seamlessly switch between models using the /model command. Chat continuity is maintained across sessions, with the system retaining the previously selected model when conversations are resumed. If you prefer Claude Sonnet 4, setting it as the default model in user settings will automatically apply to all new chat sessions, though this can be overridden with specific model selections as needed.
Figure 1: Q Developer CLI showing the model loaded for the session
Claude Sonnet 4 with Q Developer CLI in Action
After switching to Claude Sonnet 4 in Q Developer CLI, let’s explore its capabilities with a practical coding example. Here’s the prompt I’ll use for this demonstration:
Create a Python command-line to-do list app with these features:
- Add tasks with descriptions and priorities (low/medium/high)
- Mark tasks as complete by index
- Display tasks sorted by priority, then insertion order
- Show completion status ([x] done, [ ] pending)
- Handle errors for empty tasks and invalid indices
- Store tasks in memory only
Please provide the code to implement this application.
Figure 2: Q Developer CLI interface showing Claude Sonnet 4 in action
In the above demonstration, Q Developer CLI with Claude Sonnet 4 went beyond what was asked in the provided requirements in the prompt by implementing sophisticated command parsing with quoted descriptions, comprehensive error handling, and clean object-oriented design enhanced by type hints. The interface features a helpful guidance system with clear error messages, elegant enum-based priority management, and formatted output for clear task representation.
Additionally, Q Developer CLI with Claude Sonnet 4 also generated documentation in the README for the to-do application, including practical error handling examples and clear usage instructions – transforming the prompt requirements into a well-structured, user-friendly application.
Conclusion
The availability of Claude Sonnet 4 represents a significant advancement in Amazon Q Developer’s capabilities. From intricate code refactoring to streamlined documentation creation, Claude Sonnet 4 helps you accomplish both complex and routine development tasks efficiently.
Whether selecting Claude Sonnet 4 for complex tasks or using other models for specific needs, Amazon Q Developer adapts to your preferences, optimizing AI assistance while maintaining efficiency in your workflow.
The latest version(v1.11.0) of Amazon Q Developer awaits in the CLI, ready to support your development journey with enhanced model capabilities and selection options. Refer Installing Amazon Q for Command line for installation instructions.
Kirankumar Chandrashekar is a Generative AI Specialist Solutions Architect at AWS, focusing on Amazon Q Developer. Bringing deep expertise in AWS cloud services, DevOps, modernization, and infrastructure as code, he helps customers enhance their development workflows using Amazon Q Developer. Kirankumar is passionate about solving complex customer challenges and enjoys music, cooking, and traveling.
You can use these open source solutions to develop applications faster, using up-to-date knowledge of Amazon Web Services (AWS) capabilities and configurations during the build and deployment process. Whether you’re writing code in your integrated development environment (IDE), or debugging production issues, these MCP servers support AI code assistants with deep understanding of Amazon ECS, Amazon EKS, and AWS Serverless capabilities, accelerating the journey from code to production. They work with popular AI-enabled IDEs, including Amazon Q Developer on the command line (CLI), to help you build and deploy applications using natural language commands.
The Amazon ECS MCP Server containerizes and deploys applications to Amazon ECS within minutes by configuring all relevant AWS resources, including load balancers, networking, auto-scaling, monitoring, Amazon ECS task definitions, and services. Using natural language instructions, you can manage cluster operations, implement auto-scaling strategies, and use real-time troubleshooting capabilities to identify and resolve deployment issues quickly.
For Kubernetes environments, the Amazon EKS MCP Server provides AI assistants with up-to-date, contextual information about your specific EKS environment. It offers access to the latest EKS features, knowledge base, and cluster state information. This gives AI code assistants more accurate, tailored guidance throughout the application lifecycle, from initial setup to production deployment.
The AWS Serverless MCP Server enhances the serverless development experience by providing AI coding assistants with comprehensive knowledge of serverless patterns, best practices, and AWS services. Using AWS Serverless Application Model Command Line Interface (AWS SAM CLI) integration, you can handle events and deploy infrastructure while implementing proven architectural patterns. This integration streamlines function lifecycles, service integrations, and operational requirements throughout your application development process. The server also provides contextual guidance for infrastructure as code decisions, AWS Lambda specific best practices, and event schemas for AWS Lambda event source mappings.
Let’s see it in action If this is your first time using AWS MCP servers, visit the Installation and Setup guide in the AWS Labs GitHub repository to installation instructions. Once installed, add the following MCP server configuration to your local setup:
Install Amazon Q for command line and add the configuration to ~/.aws/amazonq/mcp.json. If you’re already an Amazon Q CLI user, add only the configuration.
I want to create a backend application that automatically extracts metadata and understands the content of images and videos uploaded to an S3 bucket and stores that information in a database. I'd like to use a serverless system for processing. Could you generate everything I need, including the code and commands or steps to set up the necessary infrastructure, for it to work from start to finish? - Use 02_using_converse_api.ipynb as example code for the image and video understanding.
Amazon Q CLI identifies the necessary tools, including the MCP serverawslabs.aws-serverless-mcp-server. Through a single interaction, the AWS Serverless MCP server determines all requirements and best practices for building a robust architecture.
I ask to Amazon Q CLI that build and test the application, but encountered an error. Amazon Q CLI quickly resolved the issue using available tools. I verified success by checking the record created in the Amazon DynamoDB table and testing the application with the dog2.jpeg file.
To enhance video processing capabilities, I decided to migrate my media analysis application to a containerized architecture. I used this prompt:
I'd like you to create a simple application like the media analysis one, but instead of being serverless, it should be containerized. Please help me build it in a new CDK stack.
Amazon Q Developer begins building the application. I took advantage of this time to grab a coffee. When I returned to my desk, coffee in hand, I was pleasantly surprised to find the application ready. To ensure everything was up to current standards, I simply asked:
please review the code and all app using the awslabsecs_mcp_server tools
Amazon Q Developer CLI gives me a summary with all the improvements and a conclusion.
I ask it to make all the necessary changes, once ready I ask Amazon Q developer CLI to deploy it in my account, all using natural language.
After a few minutes, I review that I have a complete containerized application from the S3 bucket to all the necessary networking.
I ask Amazon Q developer CLI to test the app send it the-sea.mp4 video file and received a timed out error, so Amazon Q CLI decides to use the fetch_task_logs from awslabsecs_mcp_server tool to review the logs, identify the error and then fix it.
After a new deployment, I try it again, and the application successfully processed the video file
I can see the records in my Amazon DynamoDB table.
To test the Amazon EKS MCP server, I have code for a web app in the auction-website-main folder and I want to build a web robust app, for that I asked Amazon Q CLI to help me with this prompt:
Create a web application using the existing code in the auction-website-main folder. This application will grow, so I would like to create it in a new EKS cluster
Once the Docker file is created, Amazon Q CLI identifies generate_app_manifests from awslabseks_mcp_server as a reliable tool to create a Kubernetes manifests for the application.
Then create a new EKS cluster using the manage_eks_staks tool.
Once the app is ready, the Amazon Q CLI deploys it and gives me a summary of what it created.
I can see the cluster status in the console.
After a few minutes and resolving a couple of issues using the search_eks_troubleshoot_guide tool the application is ready to use.
Now I have a Kitties marketplace web app, deployed on Amazon EKS using only natural language commands through Amazon Q CLI.
Get started today Visit the AWS Labs GitHub repository to start using these AWS MCP servers and enhance your AI-powered developmen there. The repository includes implementation guides, example configurations, and additional specialized servers to run AWS Lambda function, which transforms your existing AWS Lambda functions into AI-accessible tools without code modifications, and Amazon Bedrock Knowledge Bases Retrieval MCP server, which provides seamless access to your Amazon Bedrock knowledge bases. Other AWS specialized servers in the repository include documentation, example configurations, and implementation guides to begin building applications with greater speed and reliability.
As organizations increasingly adopt AI-powered tools to enhance developer productivity, your ability to effectively communicate with these assistants becomes a valuable skill. This guide explores how you can craft prompts that deliver accurate, useful results when working with Amazon Q Developer.
Your success with Amazon Q Developer depends directly on how well you communicate with it. Through my work as a Principal Specialist Solutions Architect on the Next Generation Developer Experience team at AWS, I’ve observed that developers experience varying degrees of success based primarily on their approach to prompt construction. The difference between a vague request and a well-structured prompt can be the difference between wasted time and a productivity breakthrough.
Recent McKinsey research reveals that developers can complete tasks up to twice as fast with generative AI when using proper prompting techniques [1]. Even more impressive, developers tackling complex tasks are 25-30% more likely to complete them within given time-frames when using these tools effectively. These productivity gains aren’t automatic—they depend on mastering the art and science of prompt engineering.
Based on patterns observed across numerous customer interactions, this guide provides practical techniques to help you maximize the value of your AI-assisted development experience. You’ll learn how to transform your interactions to consistently produce helpful, relevant assistance that can dramatically improve your development workflow.
Key Takeaways
Structure your prompts with clear context, specific requirements, and desired output format
Include relevant technical details about your environment and constraints
Avoid vague requests and provide specific examples when possible
Use the provided prompt template to ensure consistent results
Getting Started with Amazon Q Developer
Already using Amazon Q Developer? Great! This guide will help you get more value from your interactions. If you haven’t set up Amazon Q Developer yet, check out the getting started guide.
Understanding the Impact of Good Prompts
The rapid adoption of AI technologies makes prompt engineering skills essential for today’s developers. McKinsey’s latest global survey reveals that 65% of organizations regularly use generative AI, nearly double from their previous survey. When developers master prompt engineering, they’re 25-30% more likely to complete complex tasks within given timeframes.
What Makes an Effective Prompt?
Specific Request: State exactly what you need
Clear Background: Describe your project, requirements, and constraints
Additional Context: Provide code, configuration, or other additional context
Expected Output: Specify how you want the information presented
Here’s how this works in practice:
Poor prompt:
How do I deploy a container on AWS?
Effective prompt:
I need to deploy a containerized Node.js e-commerce application that handles
50,000 daily users with peak loads during promotional events.
Requirements:
- High availability across multiple regions
- MongoDB for persistence
- Auto-scaling capabilities

Please provide:
1. AWS architecture diagram
2. List of required services with configurations
3. Security best practices
4. Operational monitoring recommendations
Common Patterns to Avoid
Short or Vague Requests:
Add Docs
Make this better
Check this
Not much to go on here. Amazon Q Developer will likely provide generic documentation.
Another vague prompt with a generic response.
Overly Broad Questions:
How do I use AWS?
What's the best practice?
Help with Lambda
The prompt is so vague that Amazon Q Developer responds by asking clarifying questions.
The more specific prompt allows Amazon Q Developer to provide a more precise response.
Remember: The quality of information you receive directly correlates with the quality of the information you provide.
Proven Techniques for Better Results
To help you apply these principles consistently, I’ve developed a template structure that incorporates all the key elements of an effective prompt. This framework can be adapted for various scenarios and serves as a starting point for your interactions with Amazon Q Developer. While Amazon Q Developer will fill in some parts of this context (see the next post in this series), you just need to make sure this information is available.
These are the principles demonstrated in the template:
Technical Context Requirements
Specify your technology stack and versions
Include environment details
Mention compliance requirements
Define scale expectations
Example Specifications
Include relevant code snippets
Paste error messages
Reference configuration files
Show current architecture
Output Format Guidelines
Request specific documentation formats
Ask for diagrams when needed
Specify code language preferences
Indicate level of detail needed
The specification of the output format ensure the response is what you expect.
Successfully working with Amazon Q Developer requires consistent application of proven practices. These guidelines, developed through extensive customer interactions, will help you maximize the value of your AI-assisted development experience.
Start with clear business objectives
Include relevant technical constraints
Specify performance requirements
Request specific output formats
Provide examples when possible
Through extensive customer interactions, we’ve found that following these practices consistently produces better results and reduces the need for follow-up clarification.
Take Action Now
Try the prompt template with your next Amazon Q Developer request
In the next part of this series, we’ll explore advanced context management in Amazon Q Developer and dive into the new prompt catalog features. You’ll learn how to:
Build and maintain context across multiple interactions
Use the prompt catalog effectively
Handle complex, multi-step development tasks
Optimize responses for your specific use cases
Stay tuned, and start applying these techniques today to transform how you build on AWS!
In this blog post, I explore Amazon Q Developer’s latest enhancements to the IDE chat experience including increased context control, chat history and other conversation management features. On March 11th, 2025, my colleague published Take control of your code with Amazon Q Developer’s new context features detailing several improvements to the chat experience within VS Code. These included increased context transparency, the ability to select specific files or folders as context, prompt libraries for reusing prompts across conversations and projects, and project rules to help enforce coding standards and best practices across your teams.
Since then, Amazon Q Developer released additional features in VS Code to help provide users with more control over their conversations and enhance their ability to maintain development context across longer periods. These new capabilities make your interactions with Amazon Q Developer not just more efficient, but also more contextual and persistent—helping you maintain your development flow, even when work spans hours or days. Now, let’s jump in and explore some of the new features available today.
Conversation persistence
We’ve all been there—you’re deep in conversation with Amazon Q Developer, maybe you’re debugging an authentication problem, optimizing a complex database query, or designing a new API structure. You and Amazon Q Developer have been going back and forth, uncovering insights and piecing together solutions.
Then reality intervenes. You close your IDE to focus on another task, step away for a meeting, or maybe update your computer. When you finally return to your IDE, ready to dive back in, you’re met with a blank chat window. All that context, all those valuable exchanges—gone. You find yourself trying to reconstruct your train of thought, wasting precious time and momentum.
Amazon Q Developer now preserves your conversations across your IDE sessions. Instead of starting from scratch each time you open the IDE, you can now come back to your conversation and pick up right where you left off.
Conversation History Search
It isn’t just after a closed IDE session or coming back to your computer after a long-weekend that you want Amazon Q Developer to remember what you have been working on. Sometimes you need to reference a previous solution — maybe Amazon Q Developer gave you some good advice on optimizing your database queries that you want to use elsewhere, or maybe you decided to work on some front-end components so you could have fresh eyes for the API performance issue you’ve been working at.
Now, you can access your previous conversations with Amazon Q Developer by clicking on the search icon in the top right corner of your chat window. You can quickly locate specific discussions by typing keywords into the search bar, then either review the previous exchange or continue the conversation where you left off.
Fig 1 – View chat history feature in the Amazon Q Developer VS Code chat interface.
Conversation Export
But what if you need to share these insights with a teammate or want to keep a local record for future reference? You can now easily export your chat sessions as markdown files, preserving all the valuable information for offline use or collaboration. To do this, click the export button located directly to the right of the chat history button. Alternatively, when browsing your chat history, you can export individual sessions by clicking the three dots on the right side of each conversation entry.
Fig 2 – Export chat feature in the Amazon Q Developer VS Code chat interface.
Increasing your control over context
Last July, we announced the ability to use @workspace in your chat session to provide comprehensive context across your entire application within the IDE. To provide more control over what Amazon Q Developer uses as context, earlier this year we released the ability to use the @ symbol in the chat to include specific folders or files as context for your conversation.
We are now taking your level of control one step further to allow you to use @ in your conversation to find and include classes, functions, and global variables into the input context. Rather than leaving it up to Amazon Q to determine the relevant files, folders, or functions for your request, you can continue to be more explicit with your request to receive the most relevant and accurate responses.
Fig 3 – Context selection in Amazon Q Developer chat, using “@” to show relevant folders, files, functions.
Conclusion
Amazon Q Developer is continuing to evolve its features that help put developers in control of their coding experience. By offering conversation persistence, history search, and export capabilities, Amazon Q Developer works to create continuity that allows developers to maintain their momentum across sessions and easily revisit past solutions. The expanded context control features empower developers to fine-tune their interactions with Amazon Q Developer, and receive more precise and relevant responses.
To get started with these features in VS Code, visit the Amazon Q Developer Getting Started guide and explore the full range of capabilities that can help you create impressive software more efficiently.
“Everything fails, all the time” – Werner Vogels, Amazon.com CTO
In today’s digital landscape, designing applications with resilience in mind is crucial. Resiliency is the ability of applications to handle failures gracefully, adapt to changing conditions, and recover swiftly from disruptions. By integrating resilience into your application architecture, you can minimize downtime, mitigate the impact of failures, and ensure continuous availability and performance for end-users.
Amazon Q Developer, a generative AI-powered assistant for software development lifecycle (SDLC), helps design resilient architectures and enhance application availability. It recommends best practices, analyzes code, and identifies potential failure points, serving as an expert companion to strengthen application architecture and boost system availability through the following key resiliency practices.
Resilient design pattern recommendations: Access tailored design patterns like distributed systems, microservices, and serverless architectures. Amazon Q offers recommendations across redundancy, robust failovers, and circuit breakers to boost resilience in your environment.
Disaster Recovery planning: Amazon Q offers expert guidance on comprehensive disaster recovery (DR), including efficient backups, systematic restorations, strategic data replication, and seamless failovers to ensure rapid recovery from disruptions with minimal impact.
Customized Resiliency testing frameworks: Create custom templates to simulate diverse failure scenarios, such as network degradation and infrastructure outages. This streamlines thorough resilience verification across your systems.
Failure mode evaluation: Use Amazon Q to conduct comprehensive Failure Mode and Effects Analysis (FMEA) identifying infrastructure vulnerabilities and assessing their impact. Amazon Q then ranks these issues by severity, enabling you to prioritize and address the most critical risks to protect your production environment.
In the following sections, we will demonstrate how Amazon Q improves the resiliency of a foundational application architecture.
Prerequisites
To begin using Amazon Q, the following are required:
We have a three-tier web application shown below that is running on AWS in a single Availability Zone (AZ). The architecture consists of Application Layer hosted on Amazon Elastic Kubernetes Service (Amazon EKS) cluster with two Amazon Elastic Compute Cloud (Amazon EC2) nodes in a single-AZ and the Data Layer uses Amazon Relational Database Service (Amazon RDS) instance deployed in single-AZ configuration. The architecture is functional but has several limitations. It poses a single point of failure and offers limited application availability with no fault tolerance. High response times may occur because there is no caching layer in front of the database. Additionally, the lack of auto-scaling can lead to resource contention.
Basic Application Overview
Enhance Application Resiliency
Let’s explore how Amazon Q helps incorporate resiliency best practices that enhance system availability in our basic application architecture.
Resilient architecture recommendations
The initial architecture faced challenges with reliability, performance and scalability, largely due to its single-point of failure and lacked redundancy. To address this, we described the existing application design and its challenges to Amazon Q using a natural language prompt to seek resiliency recommendations.
Prompt for improving the architecture design:
I have manually setup an application that runs within an EKS cluster on two EC2 nodes in single AZ. My application is not highly available and scalable. It talks to an RDS database which is single AZ. However, there is high response times from database. Provide me only the recommendations to re-design this application architecture at each layer that will addresses all these issues.
Amazon Q analyzed the provided context and recommended improvements such as introducing Multi-AZ deployments for high availability, adding auto-scaling groups for elasticity, and incorporating caching layers to enhance performance. These targeted recommendations helped redesign the architecture to be more resilient and scalable, directly addressing the initial shortcomings.
Disaster Recovery (DR) recommendations to improve the architecture
To further enhance resiliency, we prompted Amazon Q for disaster recovery (DR) recommendations. We asked for guidance aligned with the AWS Well-Architected Framework. This built upon the previously improved architecture design.
Prompt for recommendations on Disaster Recovery (DR) and architecture based on RTO/RPO
Based on the above improvements on AWS architecture design, share recommendations for Disaster Recovery (DR) based on AWS Well Architected Framework
Optionally, we can use advanced prompts like the below with additional context:
Please provide a recommendations to redesign my application that is running on an EKS cluster with two EC2 nodes and a single-AZ RDS database, addressing high database latency, low availability, and scalability issues. Suggest improvements across all architectural layers including presentation tier, application tier and data tier to enhance performance, resiliency, and scalability. Also, recommend DR strategies aligned with the AWS Well-Architected Framework focusing on resilience, data protection, and recovery.
Amazon Q tailoring recommendations based on business requirements using AWS Well-Architected Framework
Amazon Q provided detailed DR strategies. These included multi-region configuration, backup and restore procedures, and best practices for meeting specific Recovery Time Objective (RTO) and Recovery Point Objective (RPO) requirements.
Prepare DR strategy based on RTO and RPO requirements:
Diving further, asking for a specific disaster recovery strategy that meets the application RTO requirements of 2 hours and RPO requirements of 30 minutes.
Prompt for DR strategy based on RTO/RPO values
Which DR strategy should I use if my RTO is less than 2 hours and RPO is less than 30 minutes?
Amazon Q recommending disaster recovery strategy
Amazon Q recommended a Pilot light approach, detailing the setup and components needed to achieve the specified disaster recovery objectives.
Define resiliency testing workflow, identify key metrics and tools
As we incorporate resiliency best practices into the application architecture, its is important to employ a resiliency test workflow to ensure application’s resiliency requirements are met. To do this, we are asking for guidance to define an end-to-end resiliency testing process workflow. We also want to identify the key metrics and tools needed to test the resilience of each AWS service involved in the architecture.
Prompt for defining the resiliency testing workflow:
Define the end-to-end resiliency testing process workflow. Also, identify the key metrics and tools that should be used to test the resilience of each AWS service involved in the improved architecture design.
Amazon Q offering resiliency testing best practices and tools
Amazon Q offers a step-by-step approach to define resiliency testing experiments and prepare the environment for testing.
Failure mode evaluation to prioritize resiliency tests
Failure Mode and Effects Analysis (FMEA) can further assist with designing the resiliency tests. It is a proactive method to identify potential failures in processes or systems, assess their impact, and prioritize critical issues. It evaluates failure modes across hardware, software, human factors, and external events, enabling teams to develop strategies for prevention, detection, and mitigation, ultimately enhancing system resilience.
Leveraging Amazon Q, we requested a comprehensive FMEA report that includes components, cause, effect and their respective Risk Priority Numbers (RPN). RPNs are calculated by multiplying three key factors: Severity (S), Occurrence (O), and Detection (D). It helps organizations understand and prioritize which risks to address first.
Prompt for designing the FMEA template and scoring:
Create the FMEA in tabular format with scoring for improved architecture design above keeping in mind the RTO/RPO values and provide the steps for execution as well.
Amazon Q assisting with systematic risk assessment and FMEA report
Amazon Q intelligently incorporated previously defined RTO and RPO requirements to identify critical failure scenarios and calculated RPN for each potential incident.
Enhanced Architecture Implementing Resiliency Best Practices
After identifying the key pain points in our original architecture such as single points of failure, limited scalability, and lack of automated recovery, we leveraged Amazon Q to analyze our architecture to get targeted recommendations to elevate the resiliency. By describing our requirements and challenges to Amazon Q, we received actionable guidance on AWS best practices and service configurations, which we then implemented to transform our infrastructure for high resilience and availability.
Resilient Application Architecture
The original Application Layer was running in a single Availability Zone without auto-scaling, leading to potential downtime and performance bottlenecks. Amazon Q recommended distributing Amazon EKS worker nodes across multiple Availability Zones and enabling the Cluster Autoscaler to dynamically adjust node capacity based on traffic patterns. Additionally, it suggested implementing horizontal pod autoscaling within Amazon EKS to automatically scale application resources according to CPU utilization and custom metrics. Following these recommendations, we deployed Amazon EKS worker nodes across three Availability Zones, configured Cluster Autoscaler and horizontal pod autoscaling, and integrated an Application Load Balancer, to intelligently distribute incoming traffic. These changes significantly improved scalability, fault tolerance, and performance.
The Data Layer initially relied on a single-instance Amazon RDS deployment, which posed a risk of downtime and limited read performance. Upon review, Amazon Q advised implementing a Multi-AZ Amazon RDS configuration to enable automated failover and improve availability. It also recommended deploying read replicas to offload read-heavy workloads and enhance performance. Furthermore, Amazon Q suggested adding a Multi-AZ Amazon ElastiCache for Redis to reduce database load and speed up data access. We incorporated these recommendations, resulting in a more resilient and performant data layer capable of handling failover scenarios and scaling read operations efficiently.
The Presentation Layer lacked an optimized content delivery mechanism and comprehensive security controls. Amazon Q recommended integrating Amazon CloudFront as a content delivery network to accelerate the delivery of static content and reduce load on application servers. It also suggested deploying AWS WAF to protect against common web exploits. To improve operational visibility, Amazon Q emphasized the importance of comprehensive monitoring using Amazon CloudWatch, combining logs, metrics, and traces for rapid issue detection and resolution. Implementing these recommendations enhanced both the performance and security posture of the presentation layer.
Conclusion
Amazon Q Developer transforms how teams build resilient applications by serving as your expert companion throughout the development journey. Its guidance helps create systems that excel in resilience, scalability, and availability—critical factors for today’s demanding digital landscape. Amazon Q goes beyond theoretical advice by providing practical, step-by-step implementation guidance. In the above, we’ve witnessed how Amazon Q’s expertise can transform basic architectures into robust, failure-resistant systems. Its recommendations such as Multi-AZ redundancy, elastic scaling, strategic caching, and proactive resilience testing create applications that maintain performance and availability even during significant disruptions.
Ready to strengthen your applications against unexpected challenges? Harness Amazon Q’s capabilities to create resilient infrastructure that consistently delivers for your customers, regardless of conditions. Unlock the full potential of your AWS infrastructure and deliver uninterrupted service to your customers, today. To learn more about Amazon Q refer to the documentation.
About the authors:
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
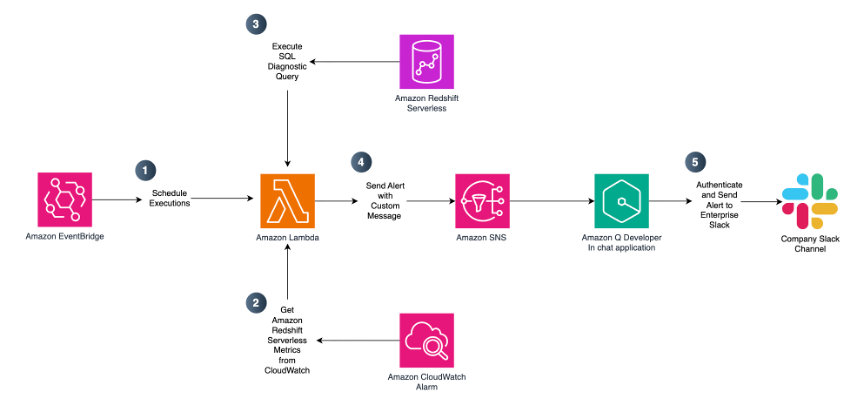
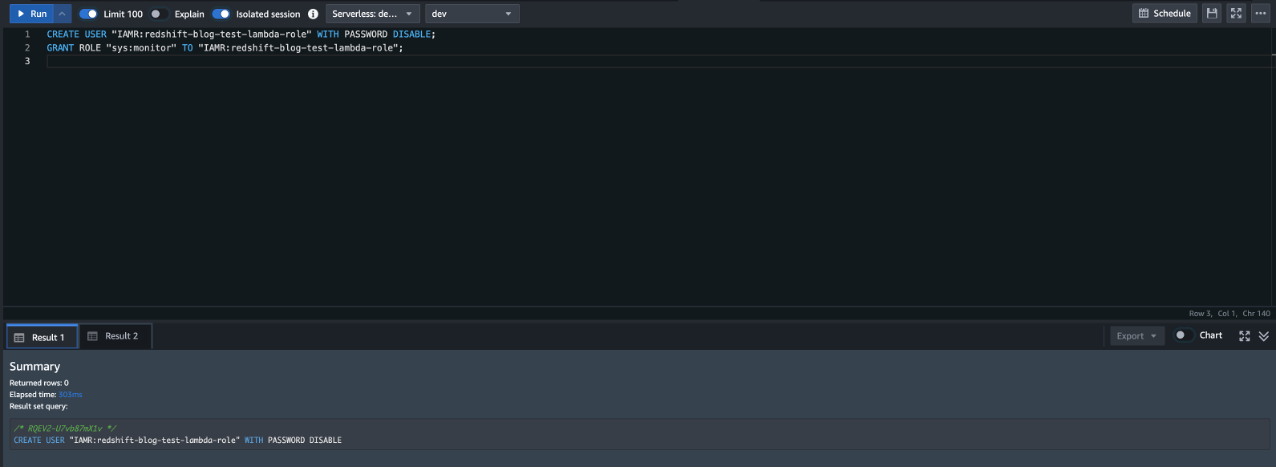
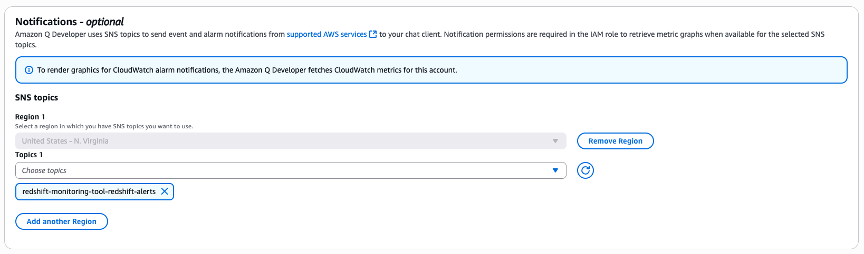
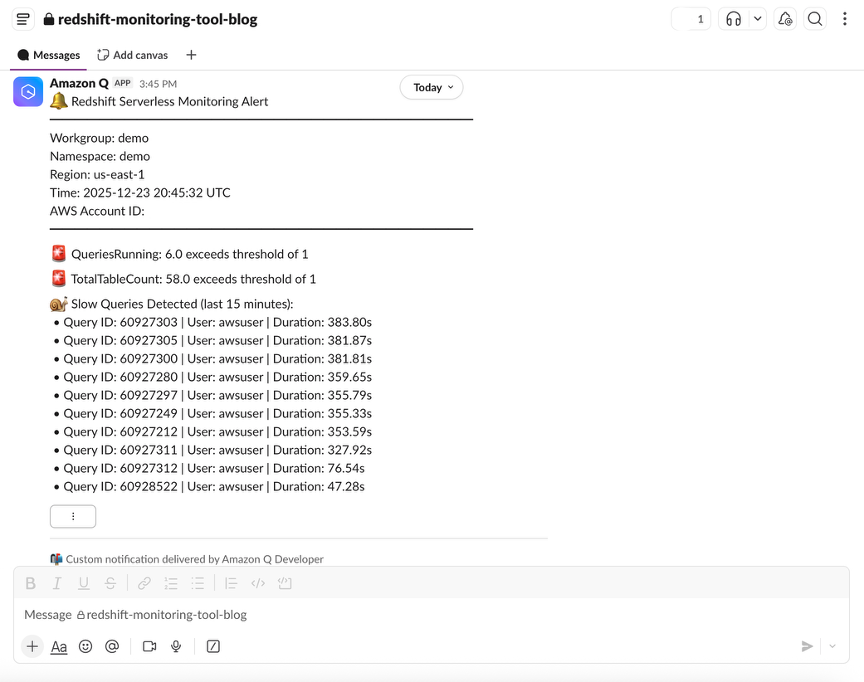
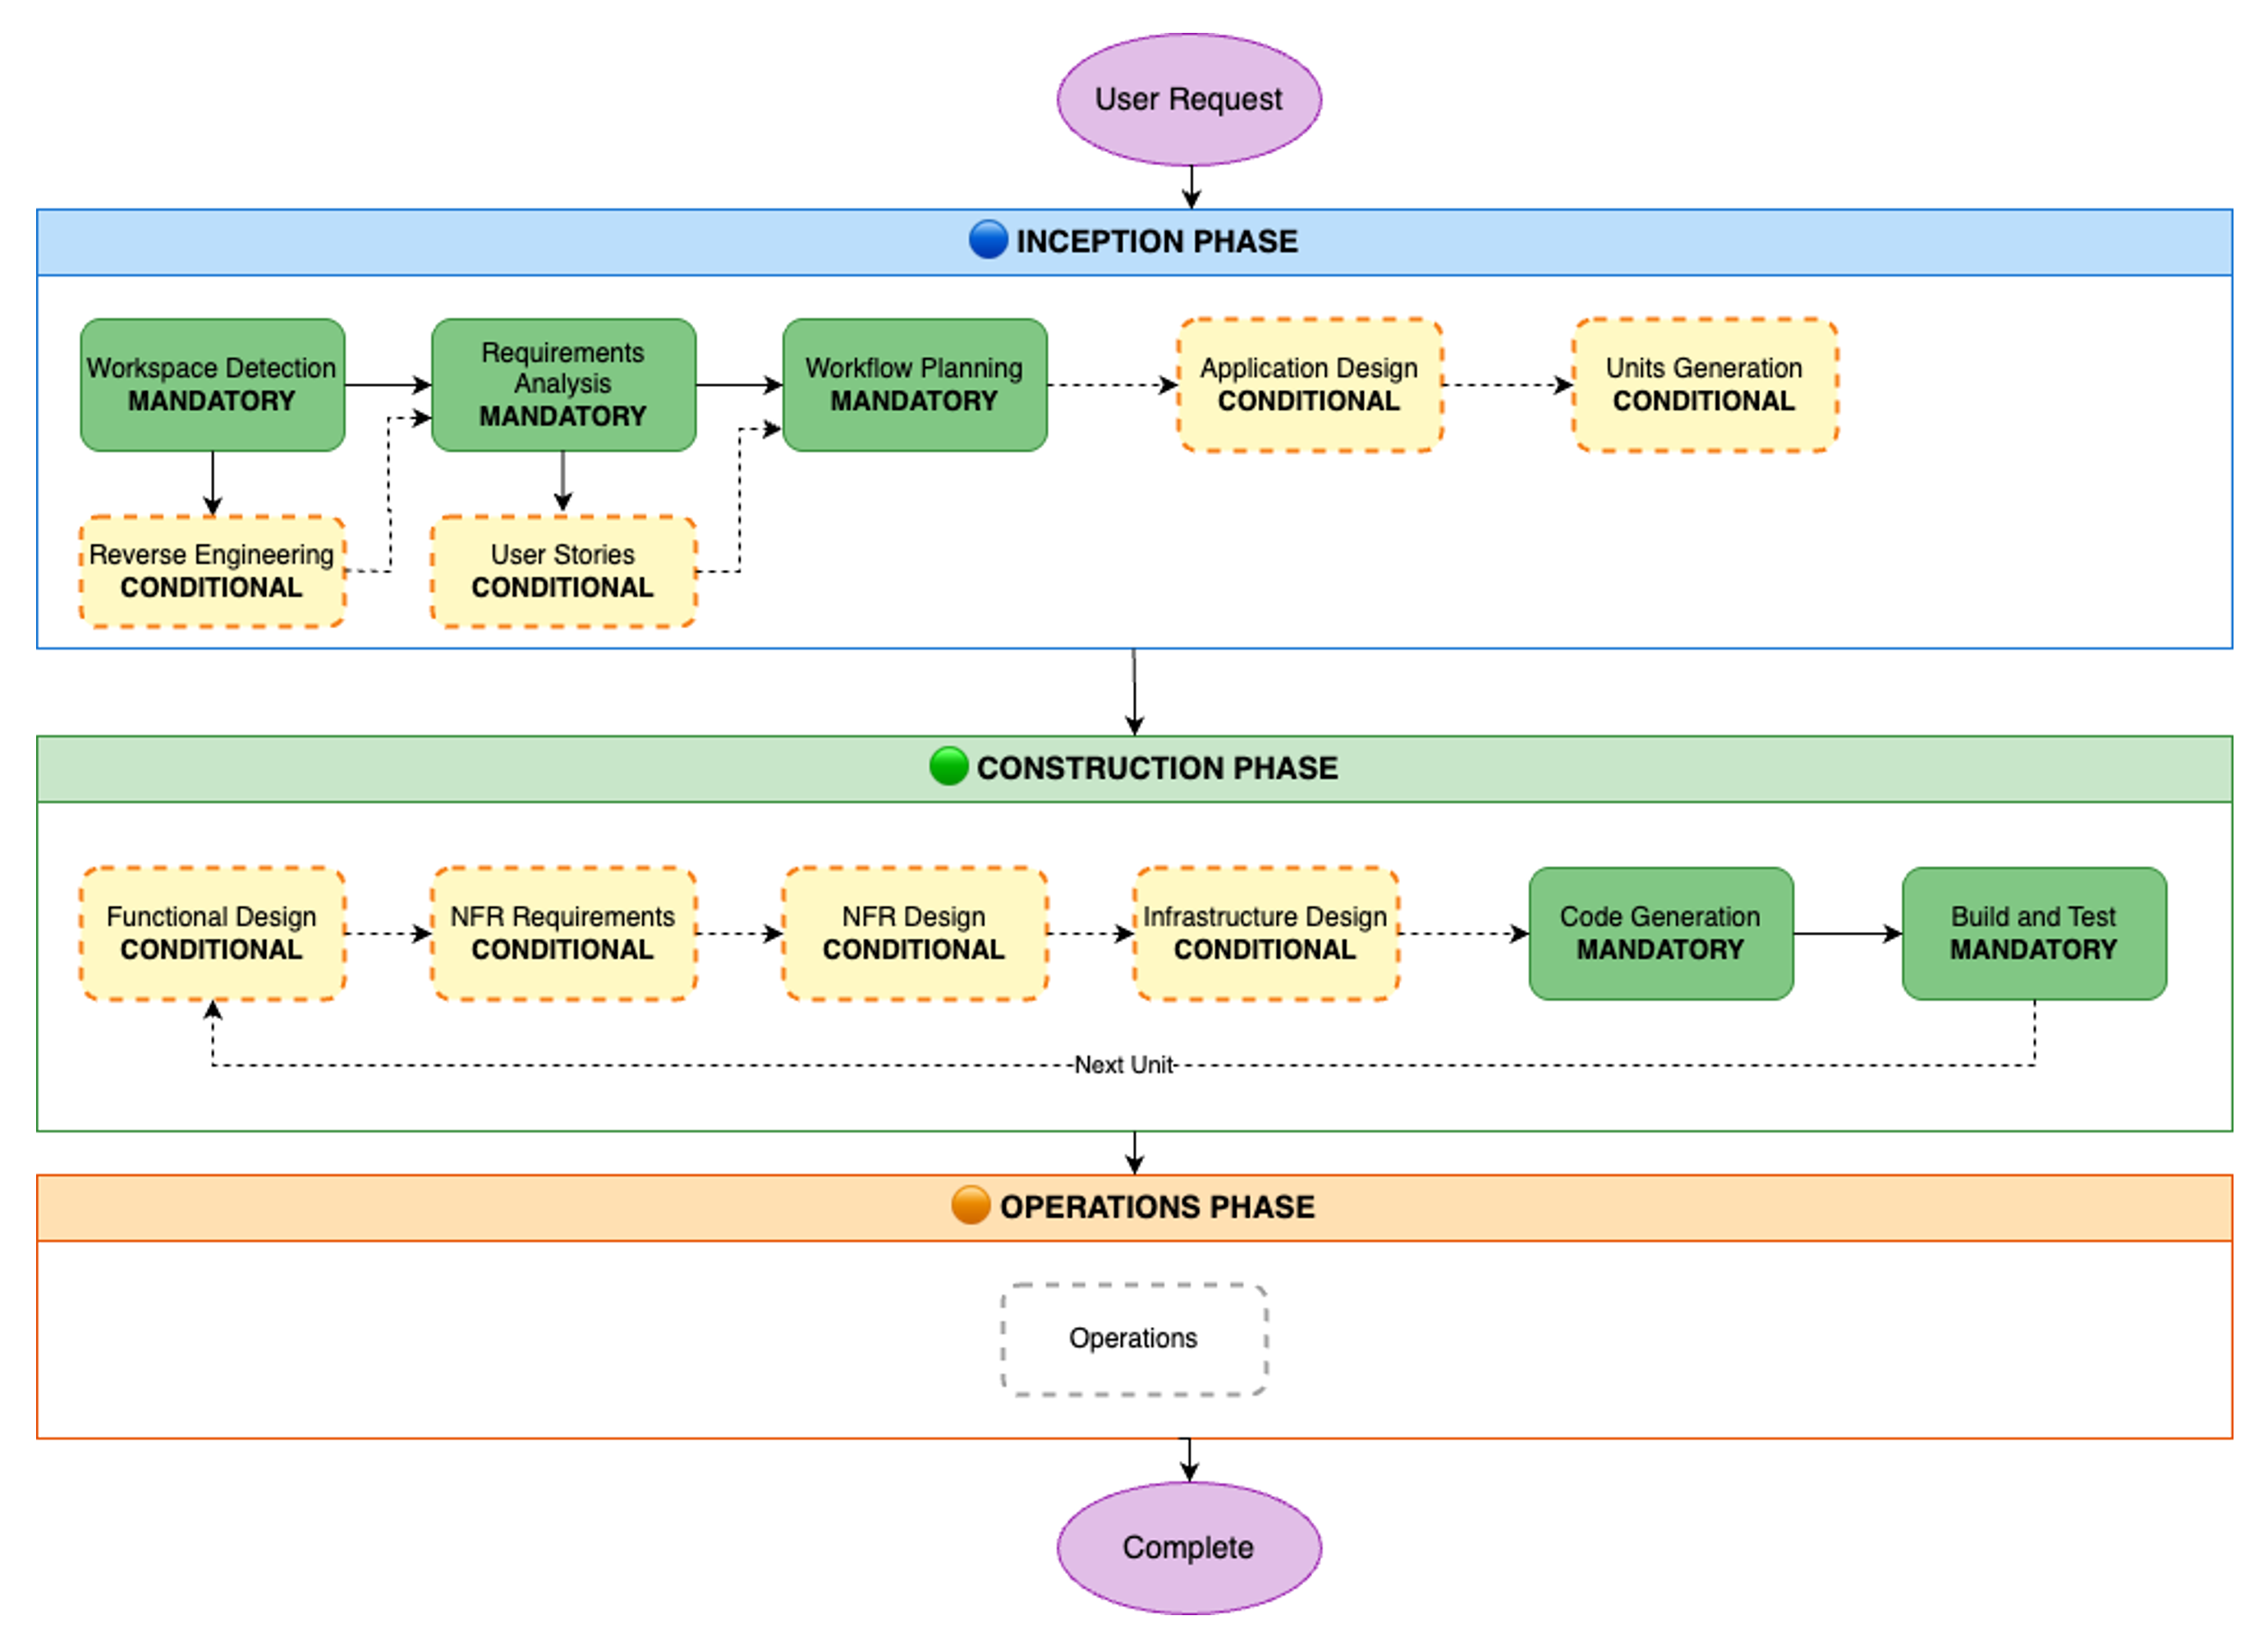

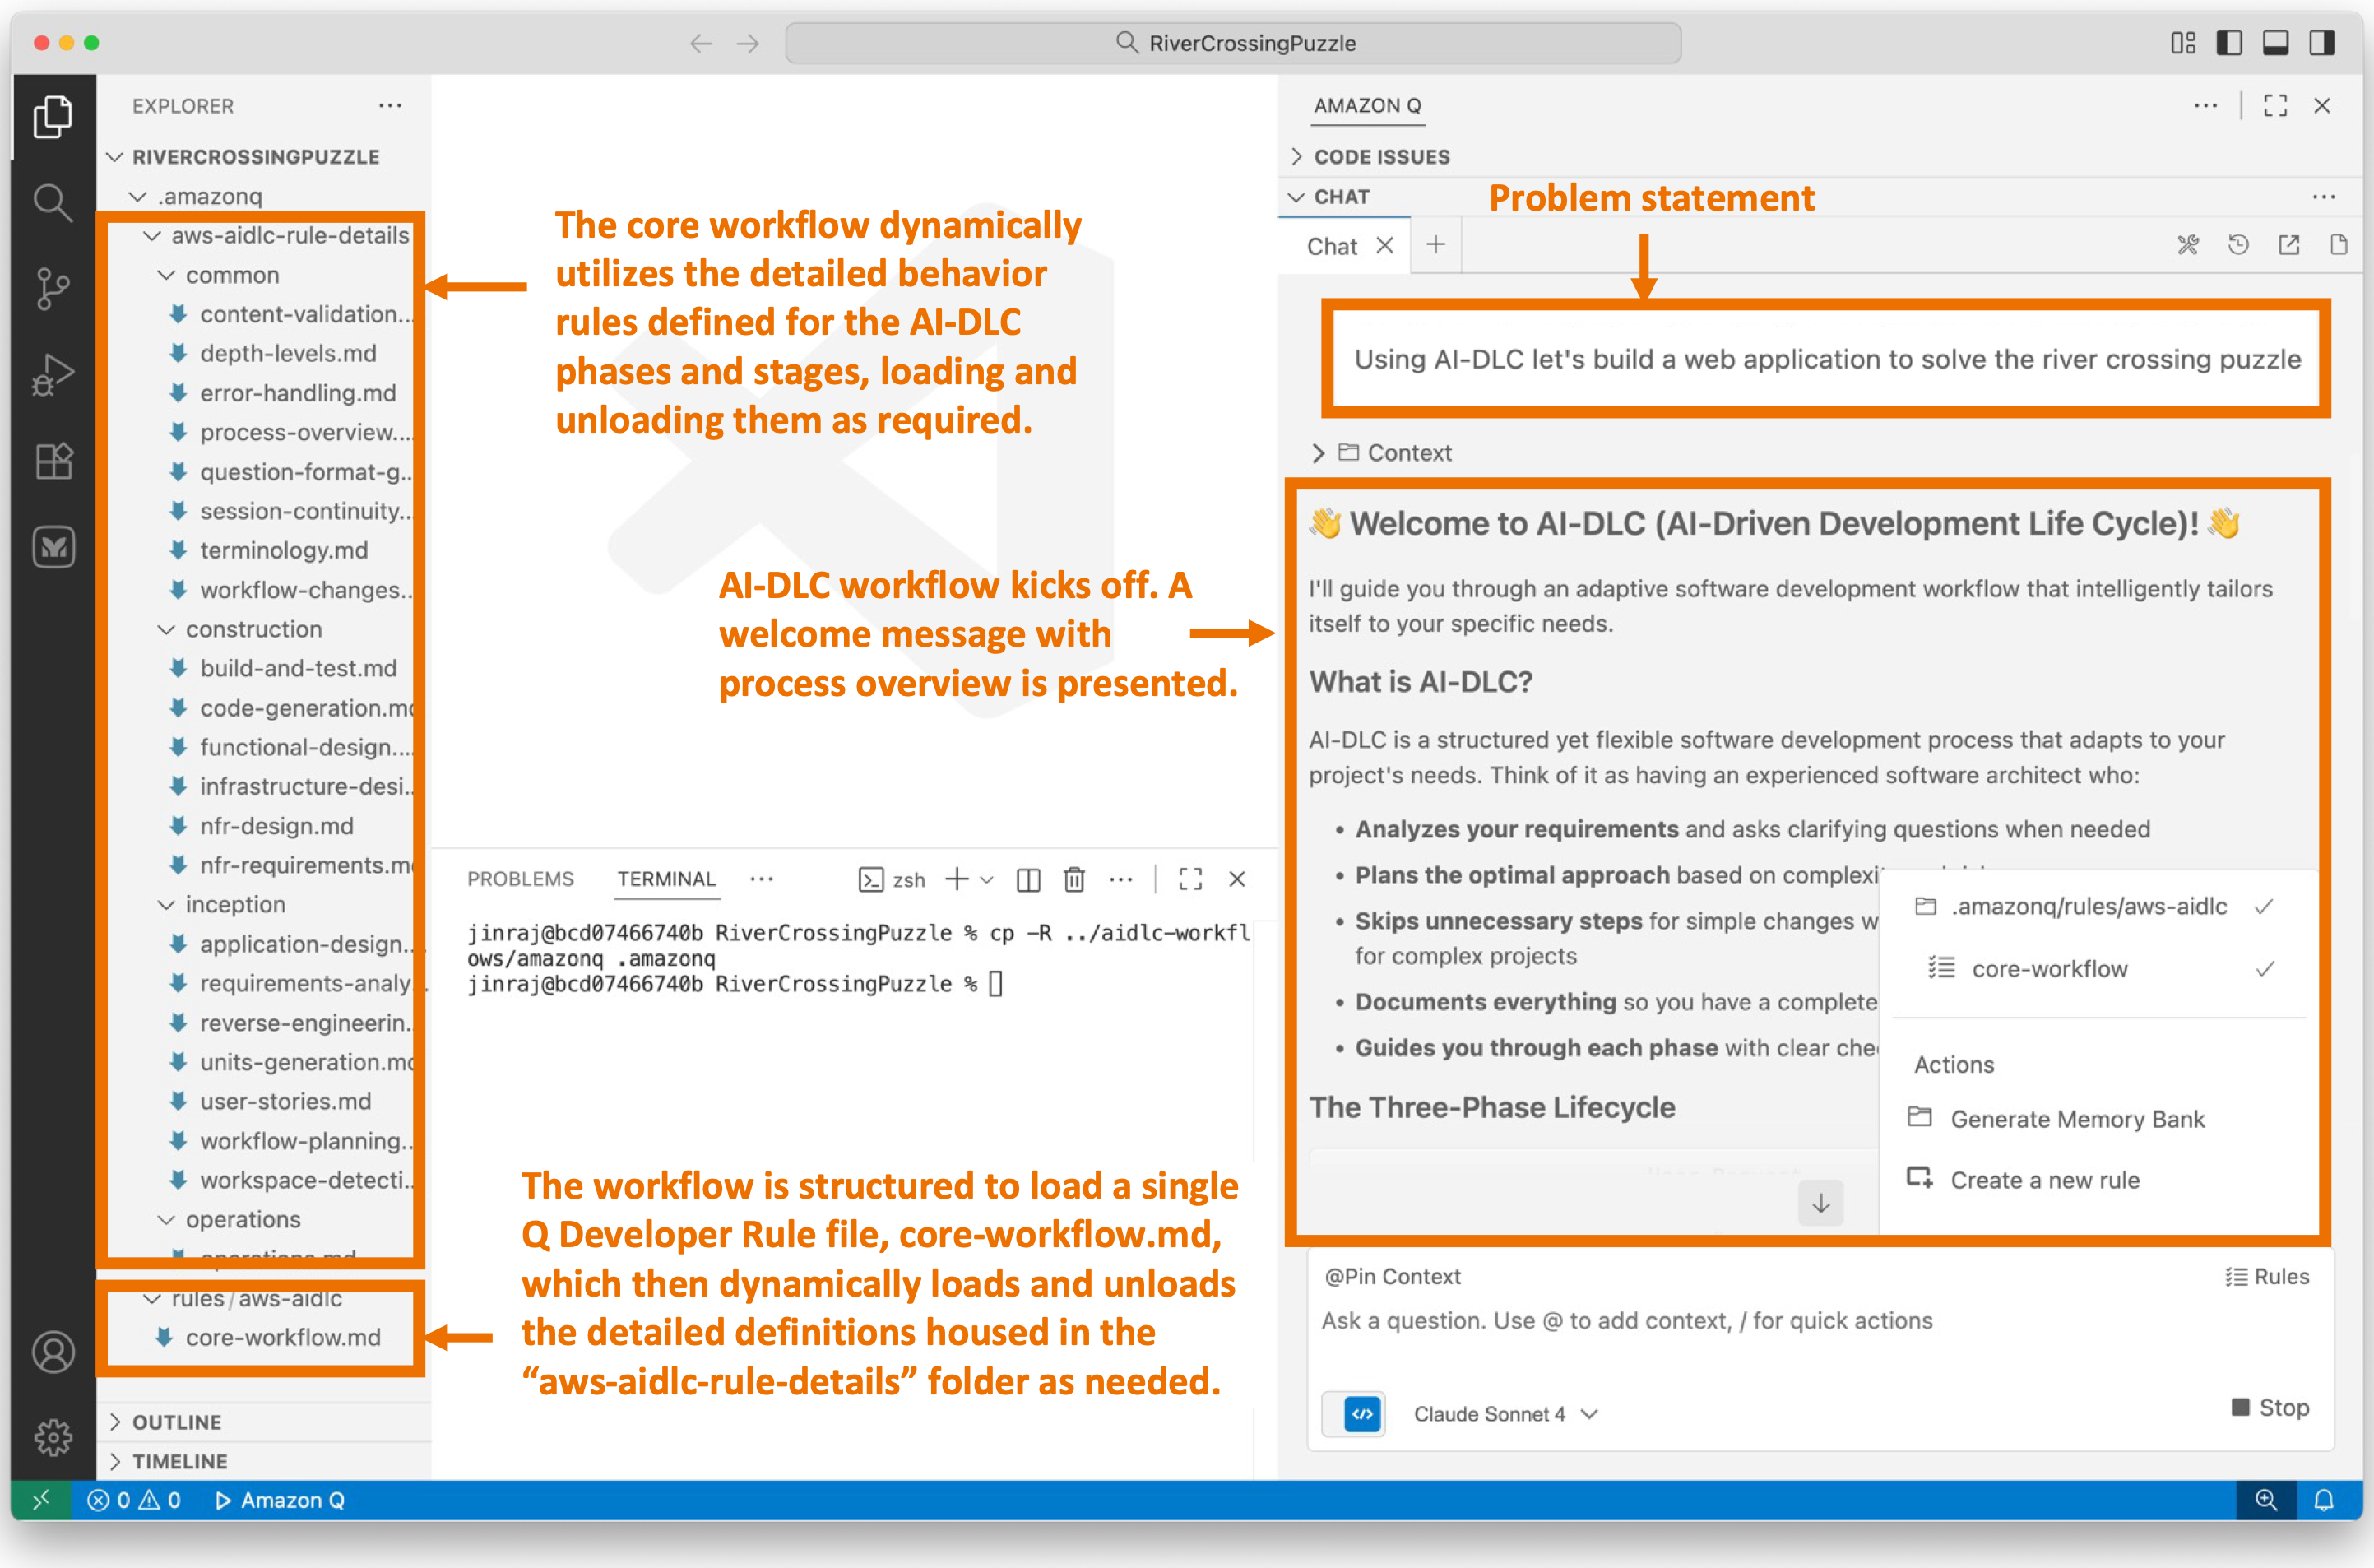


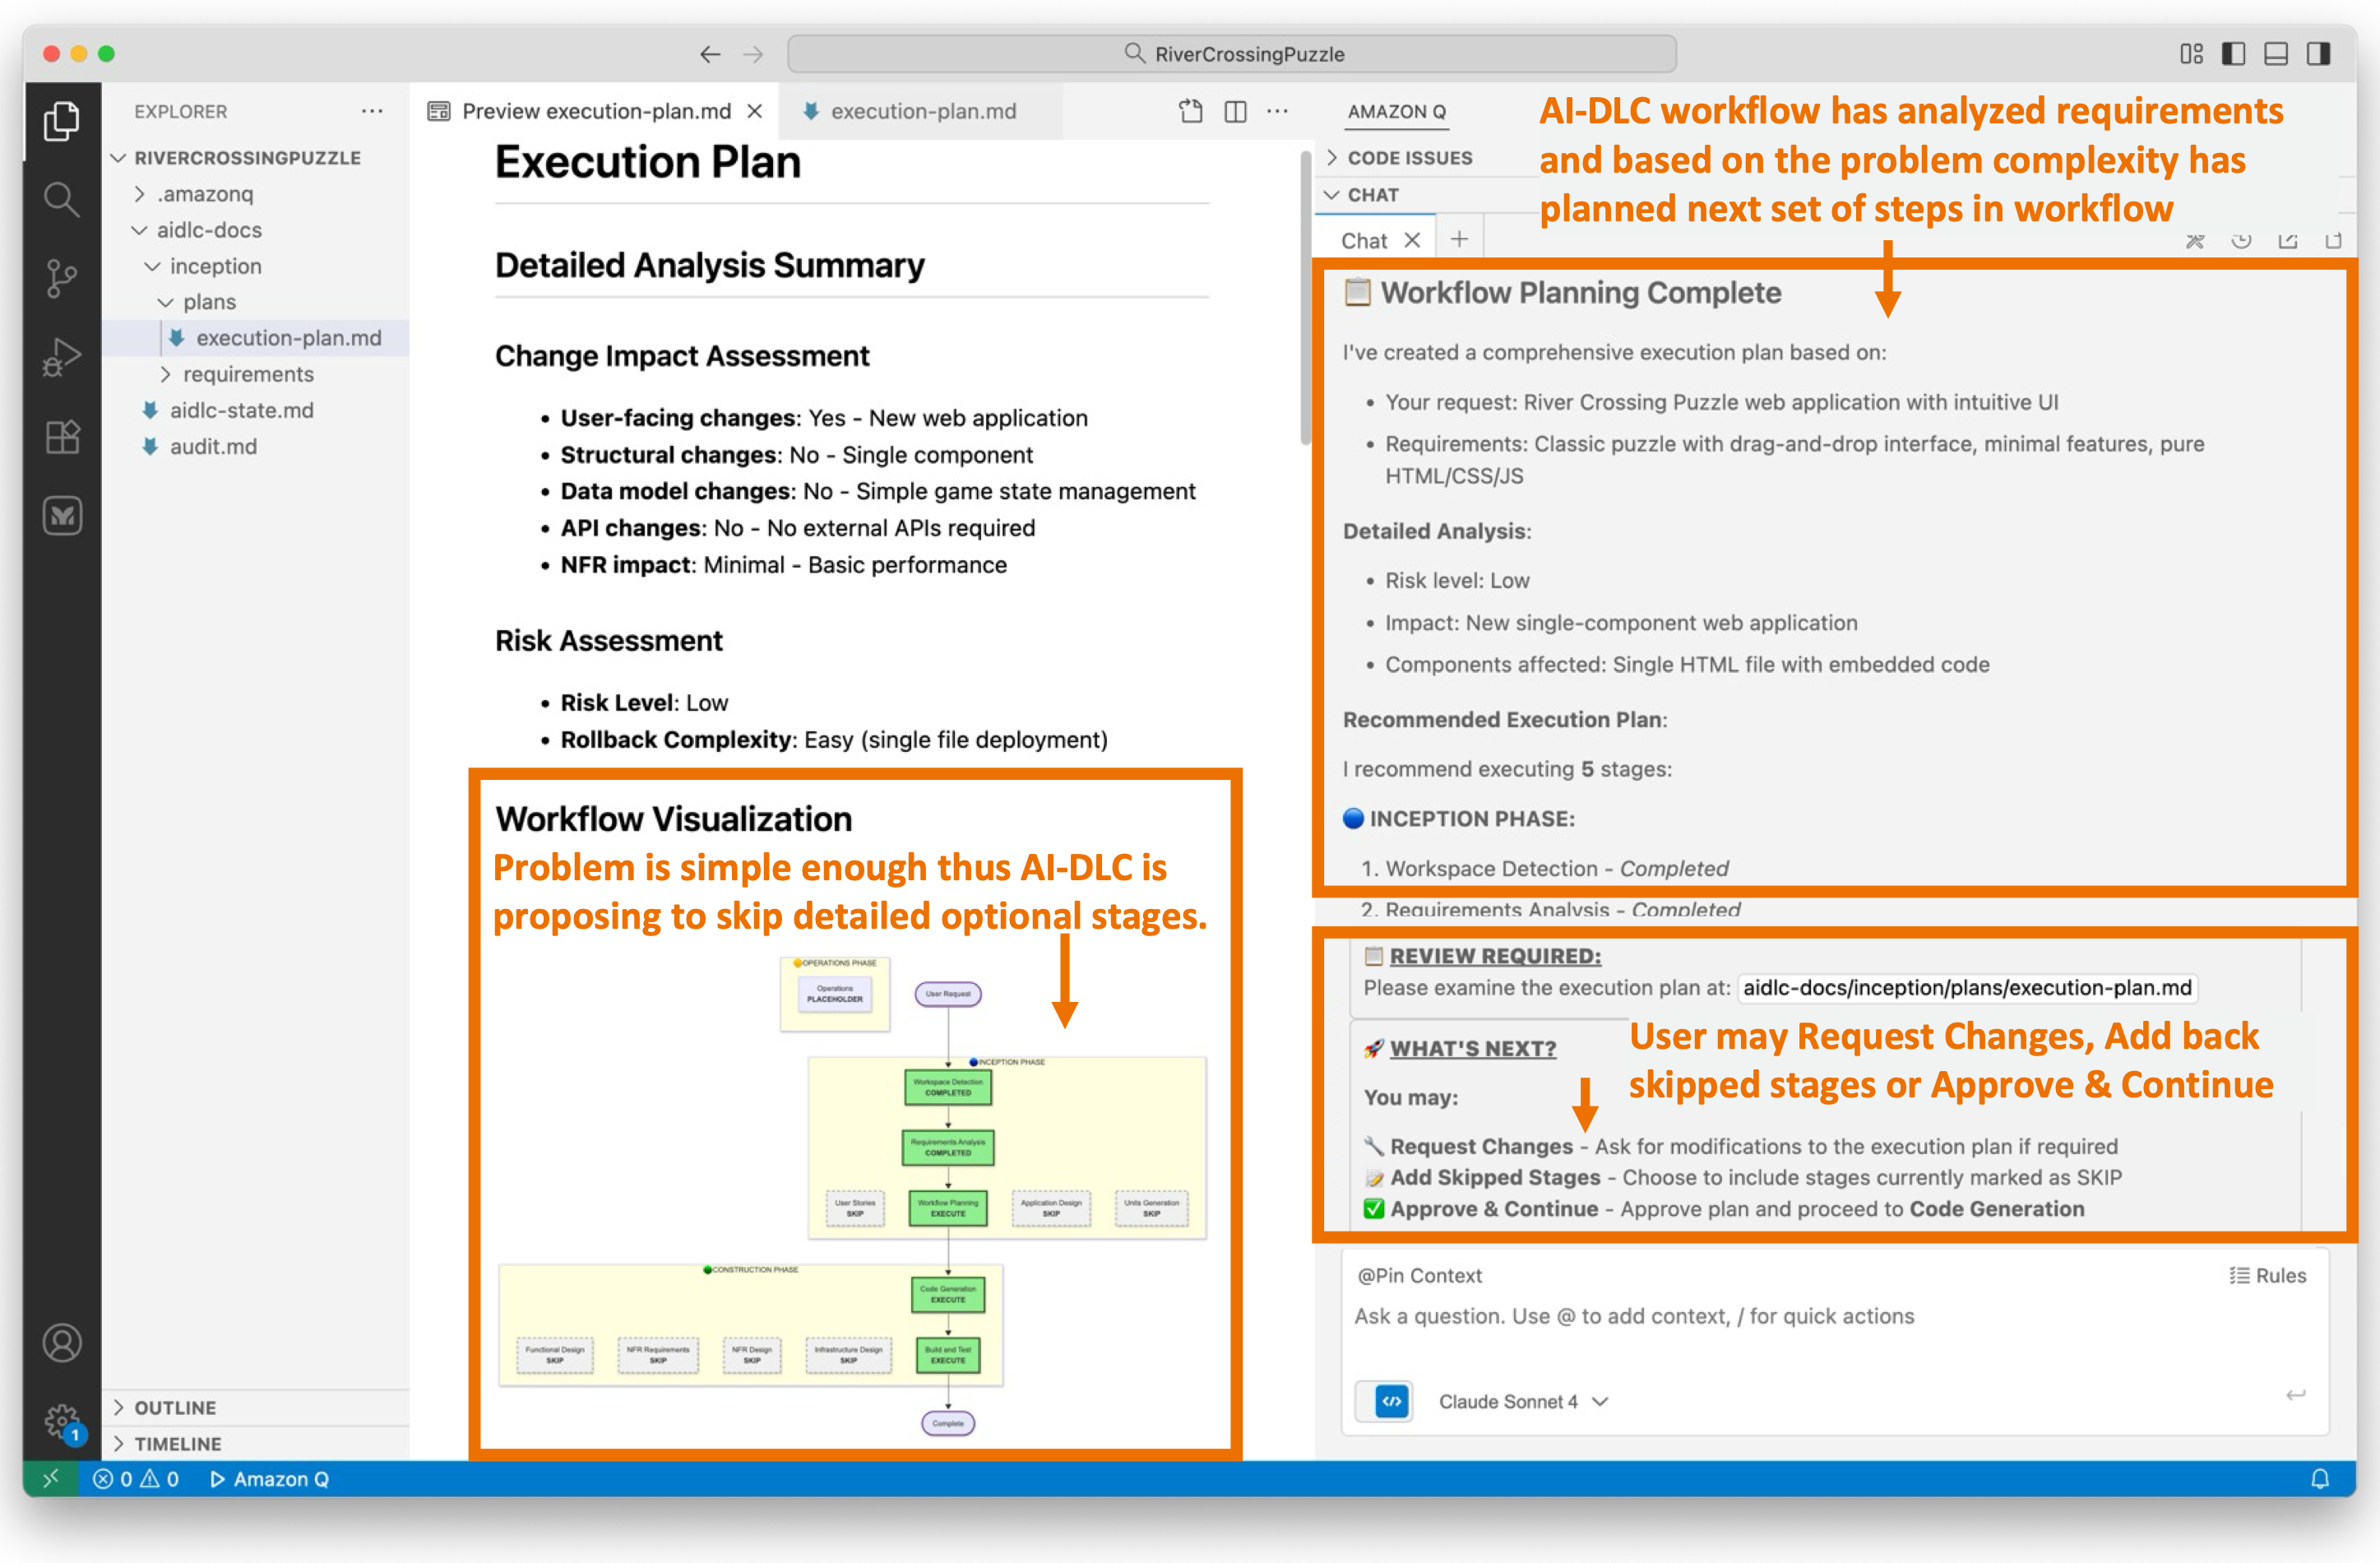
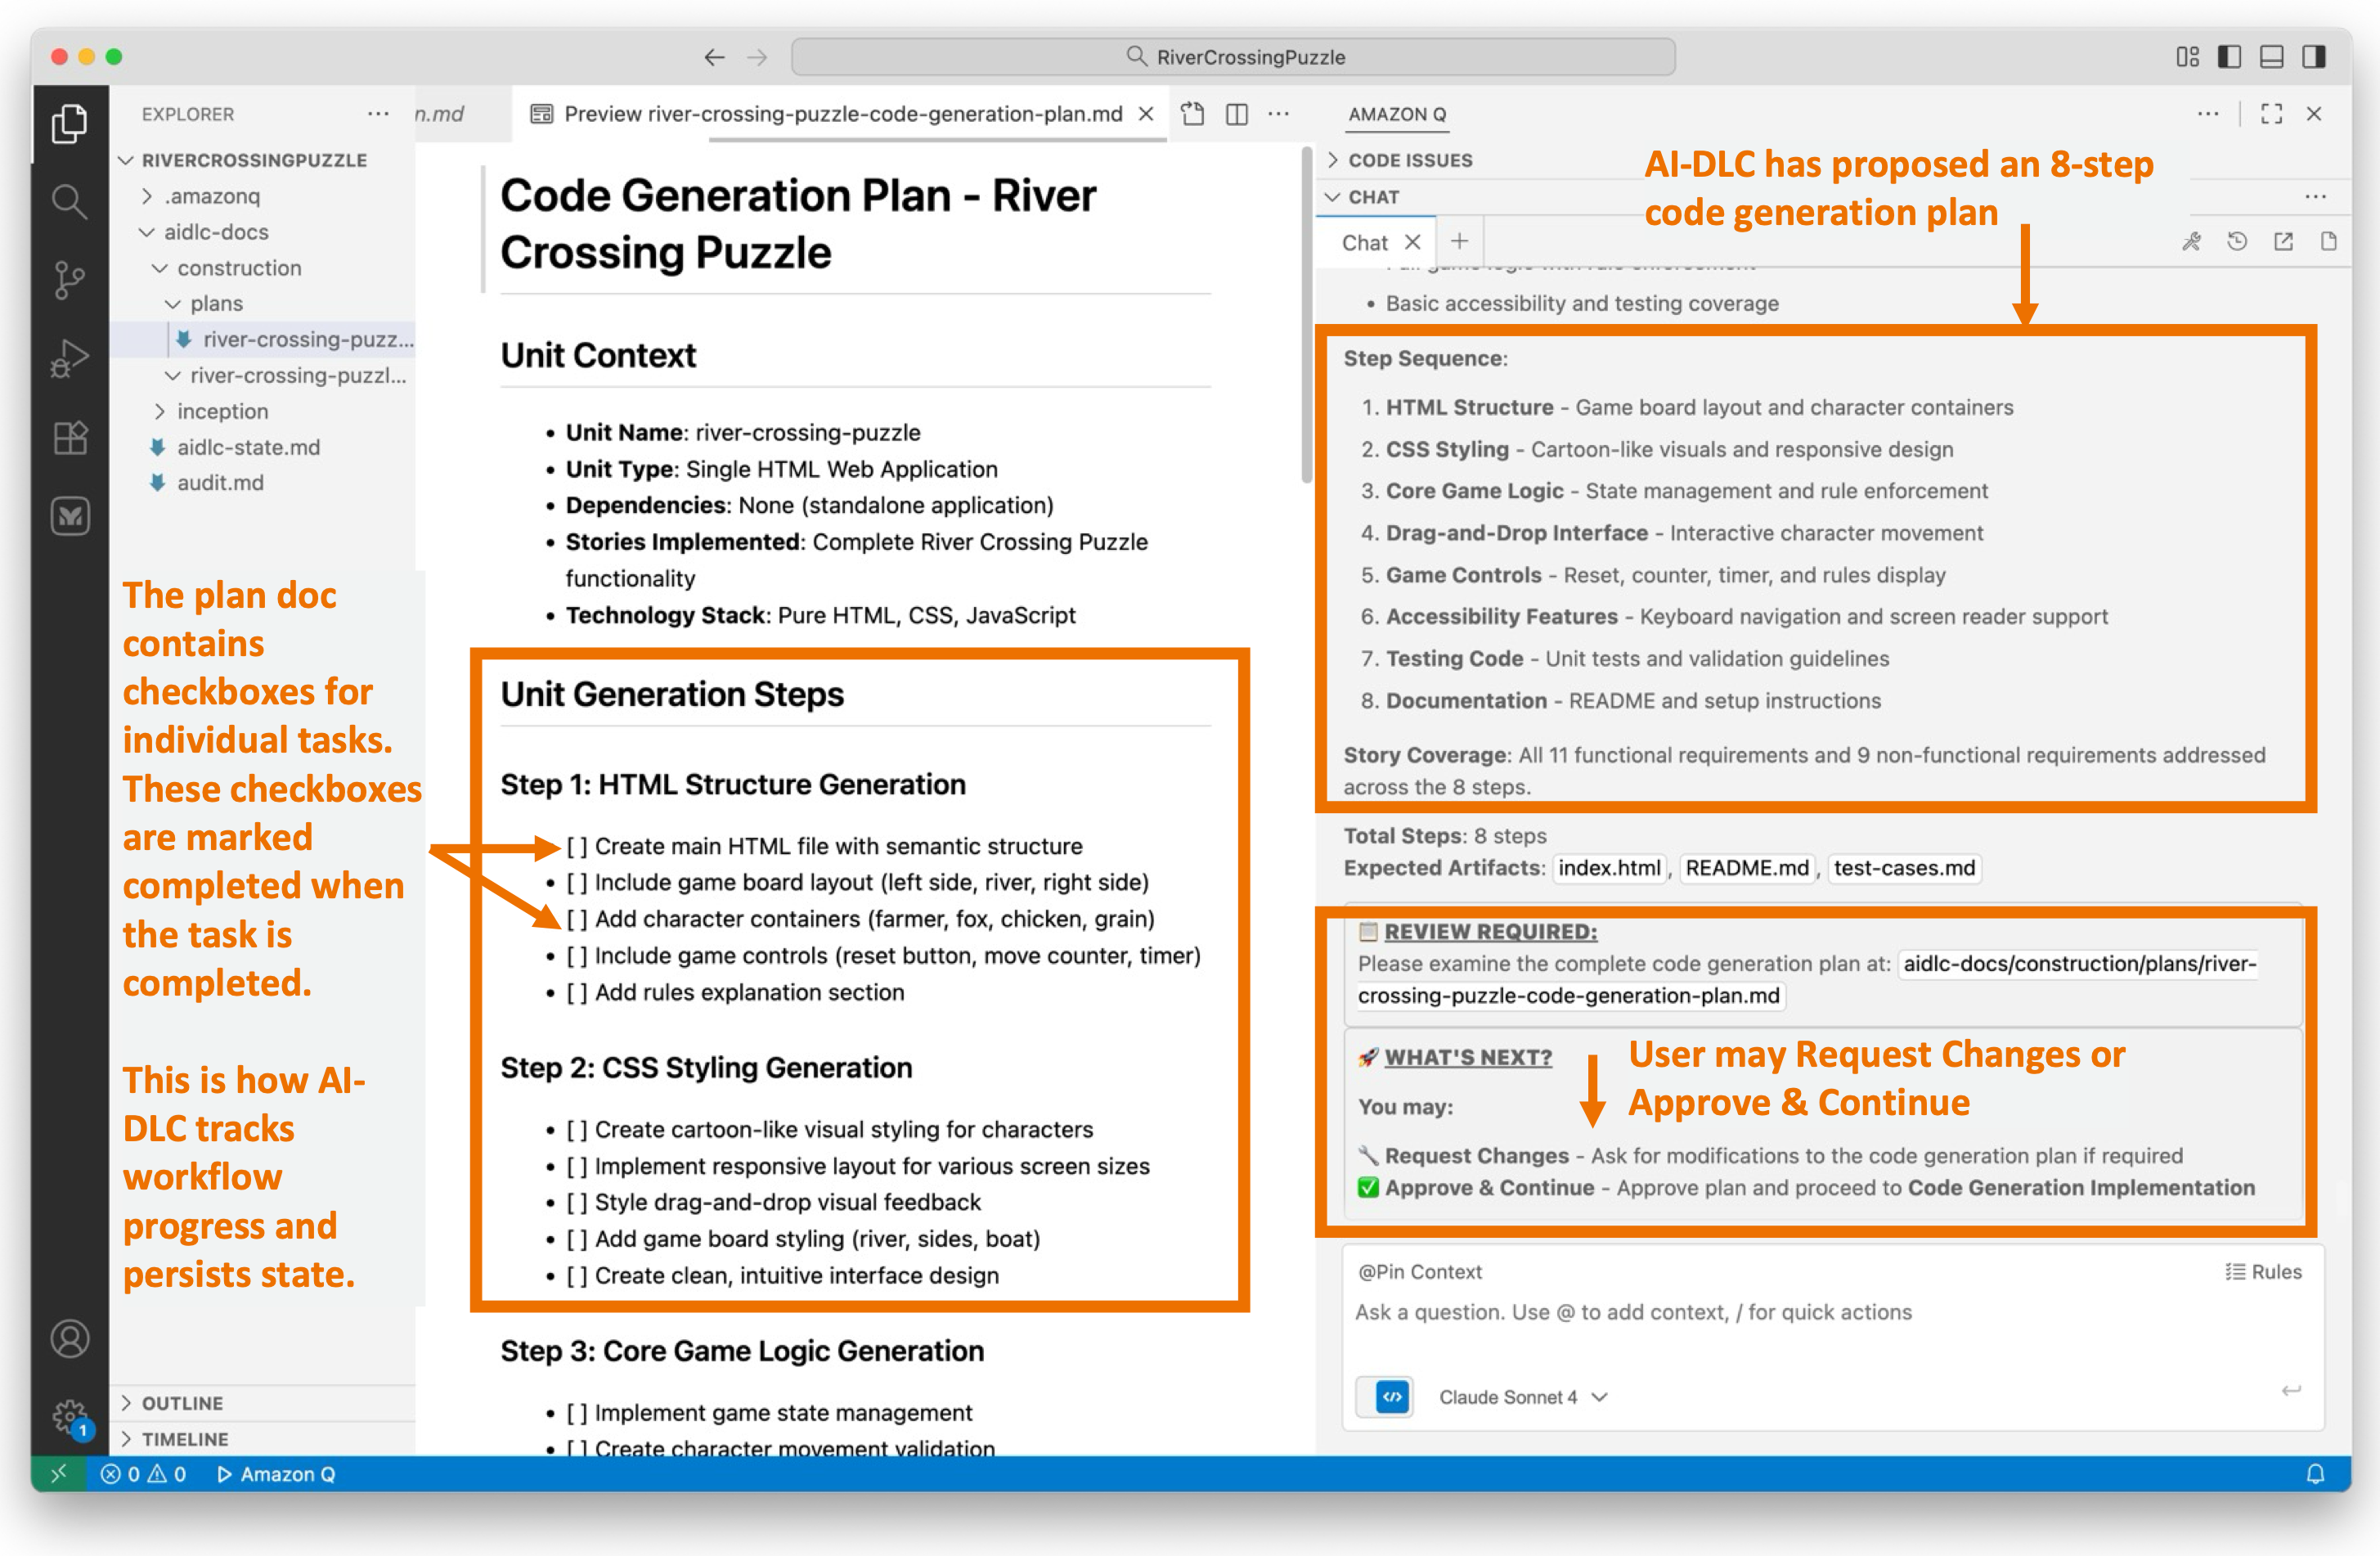
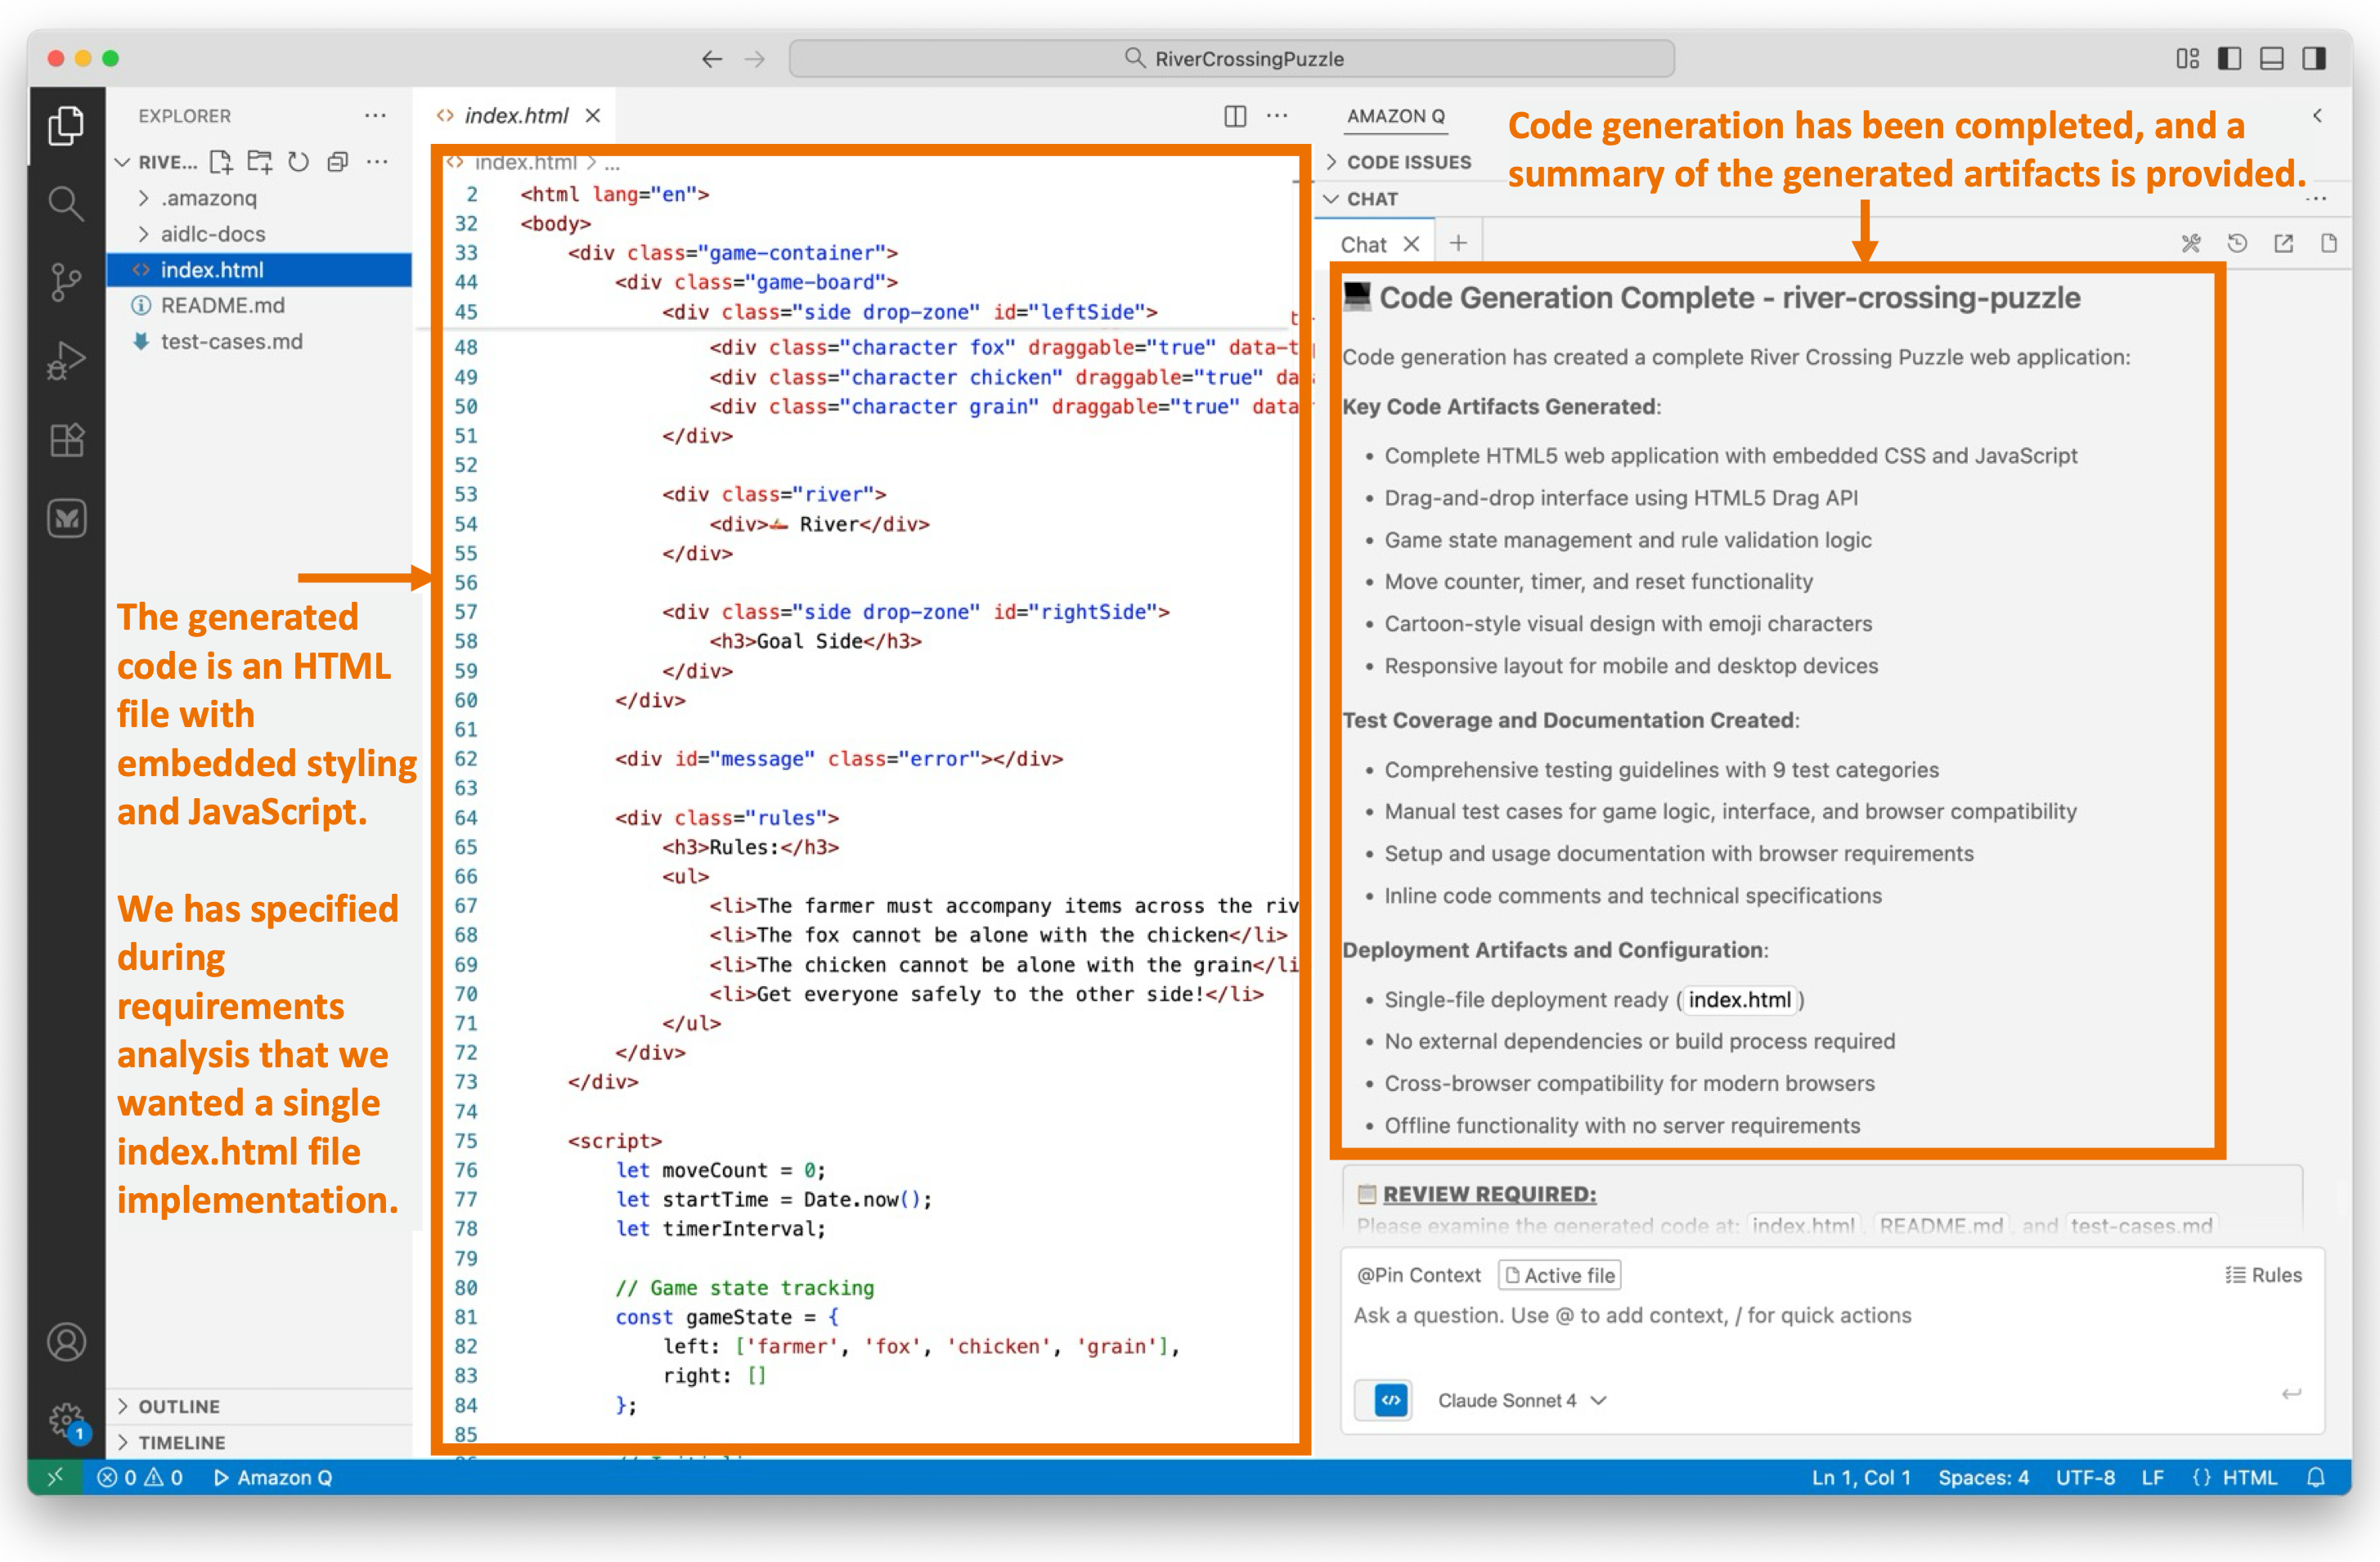
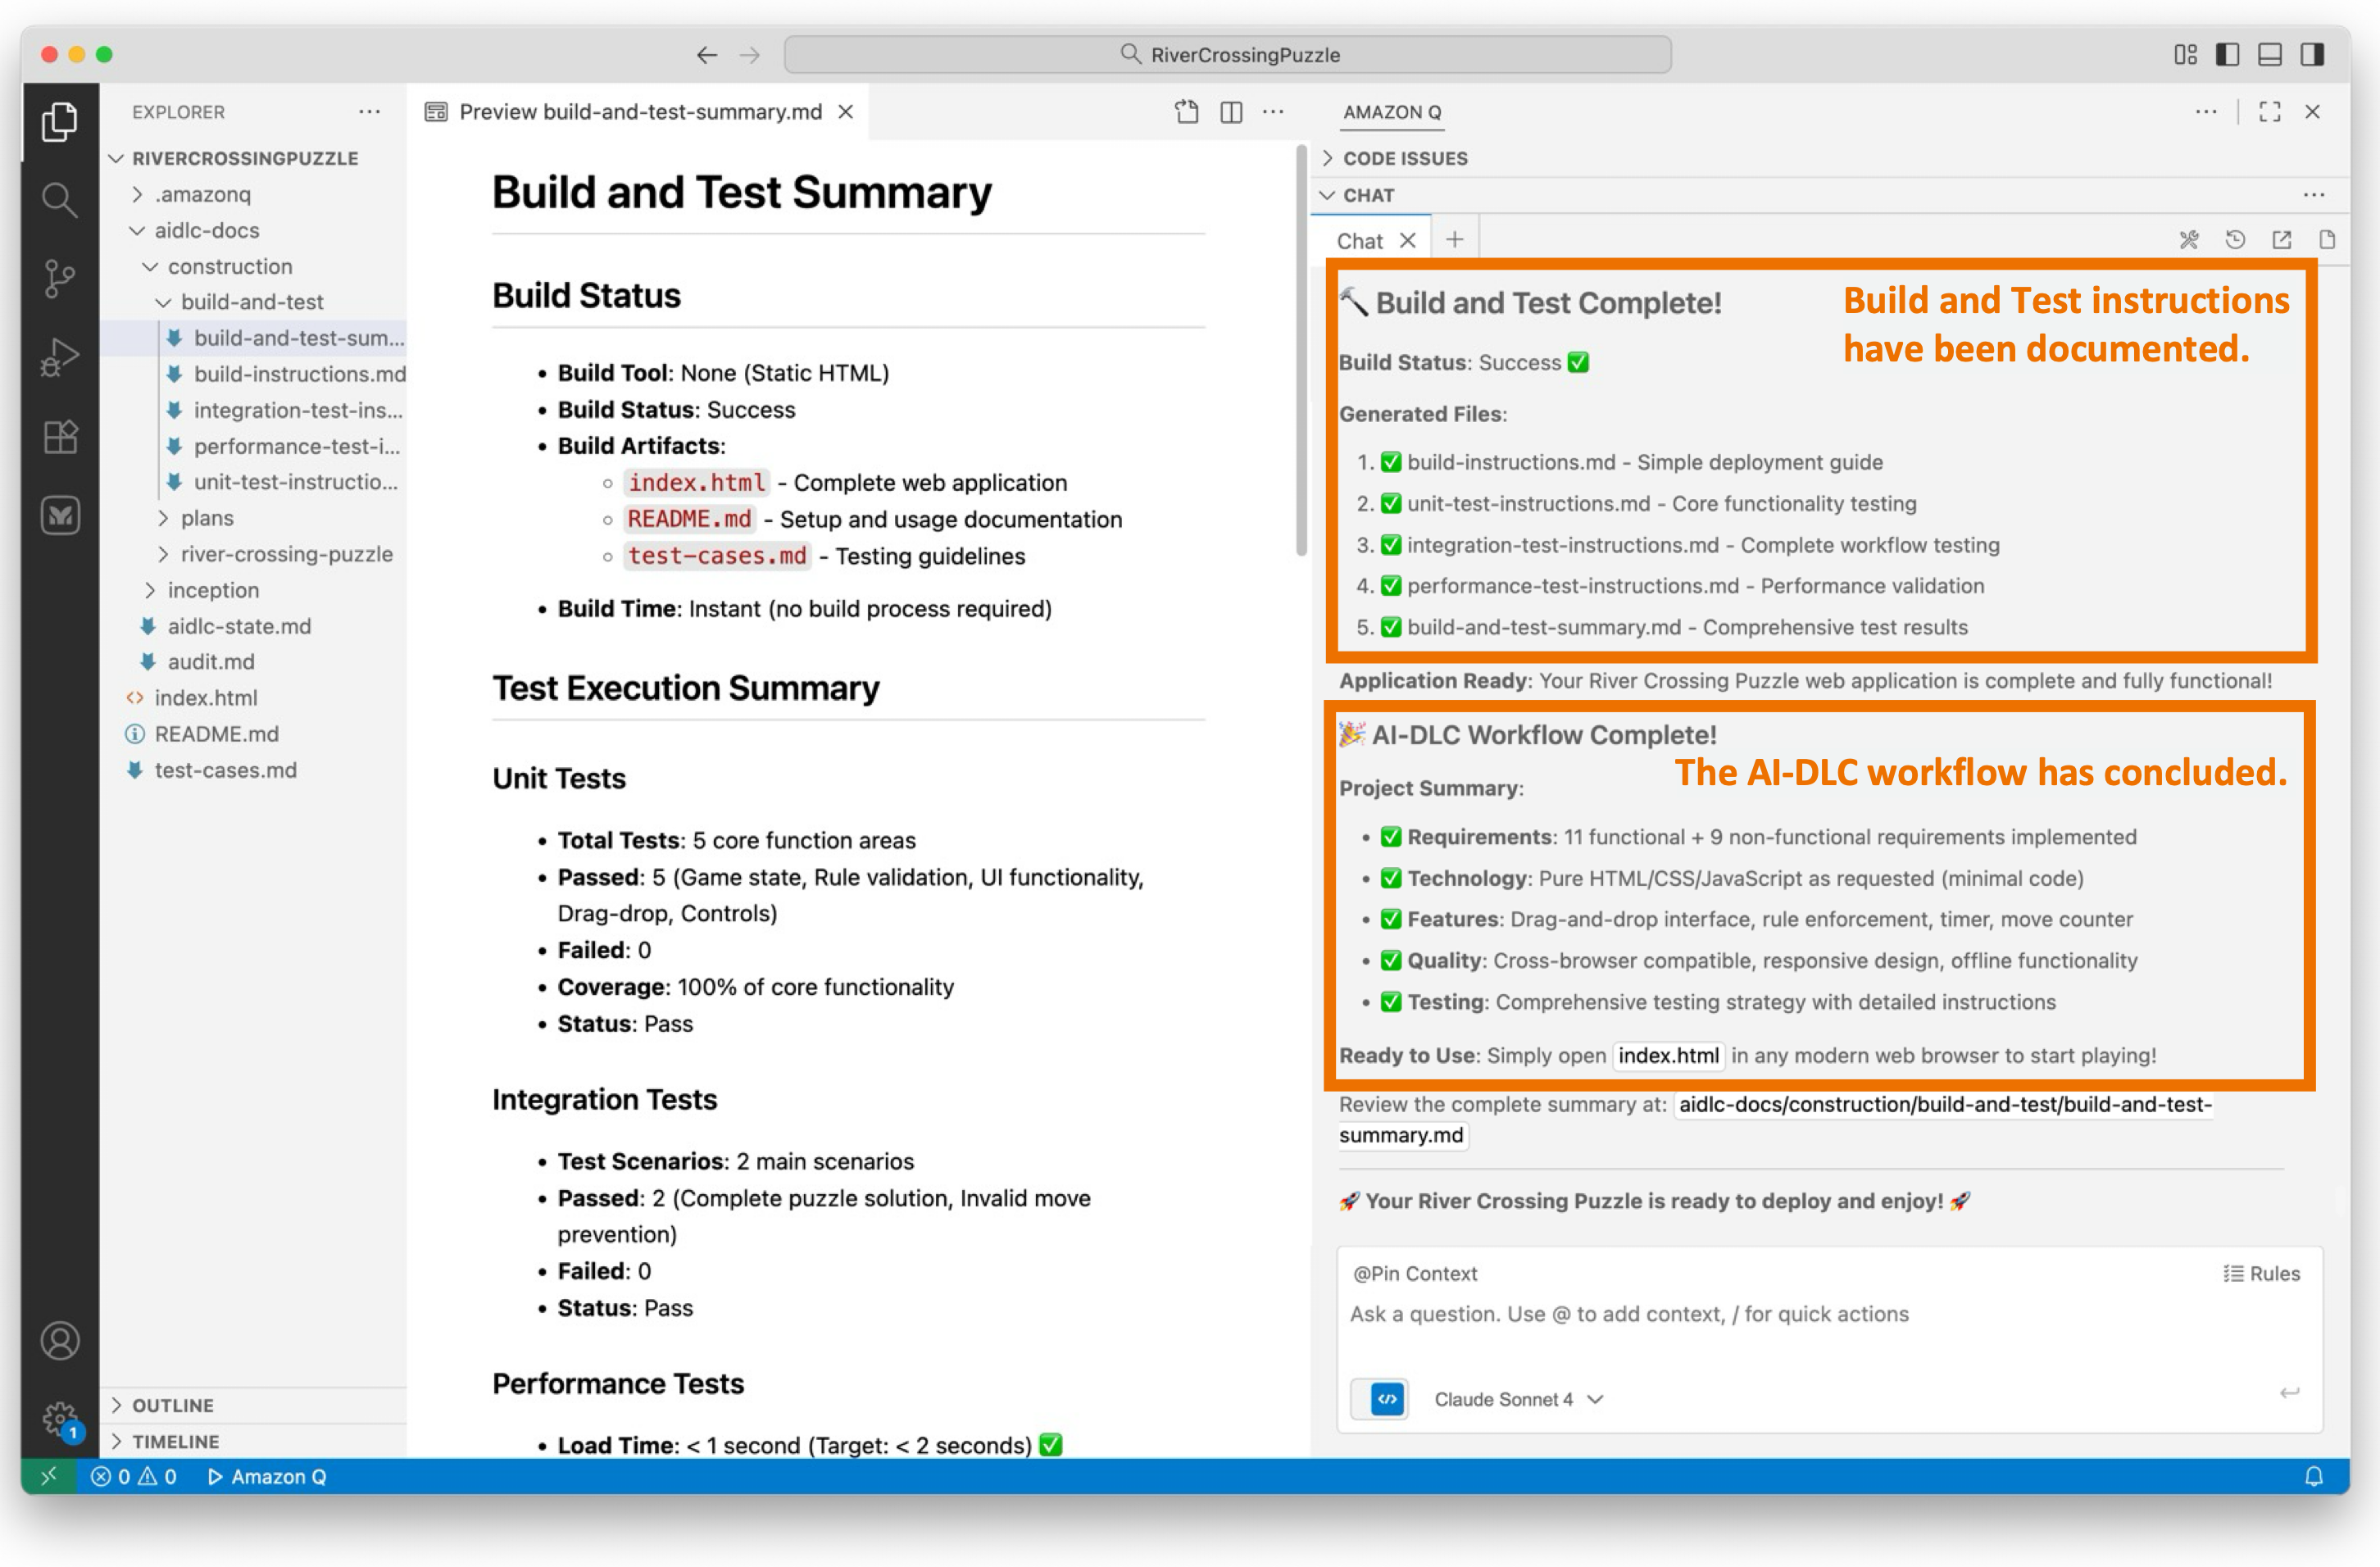

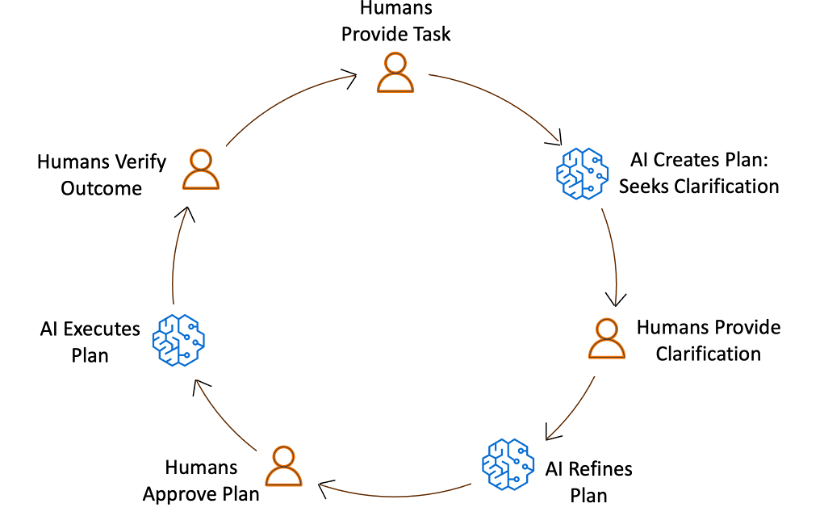
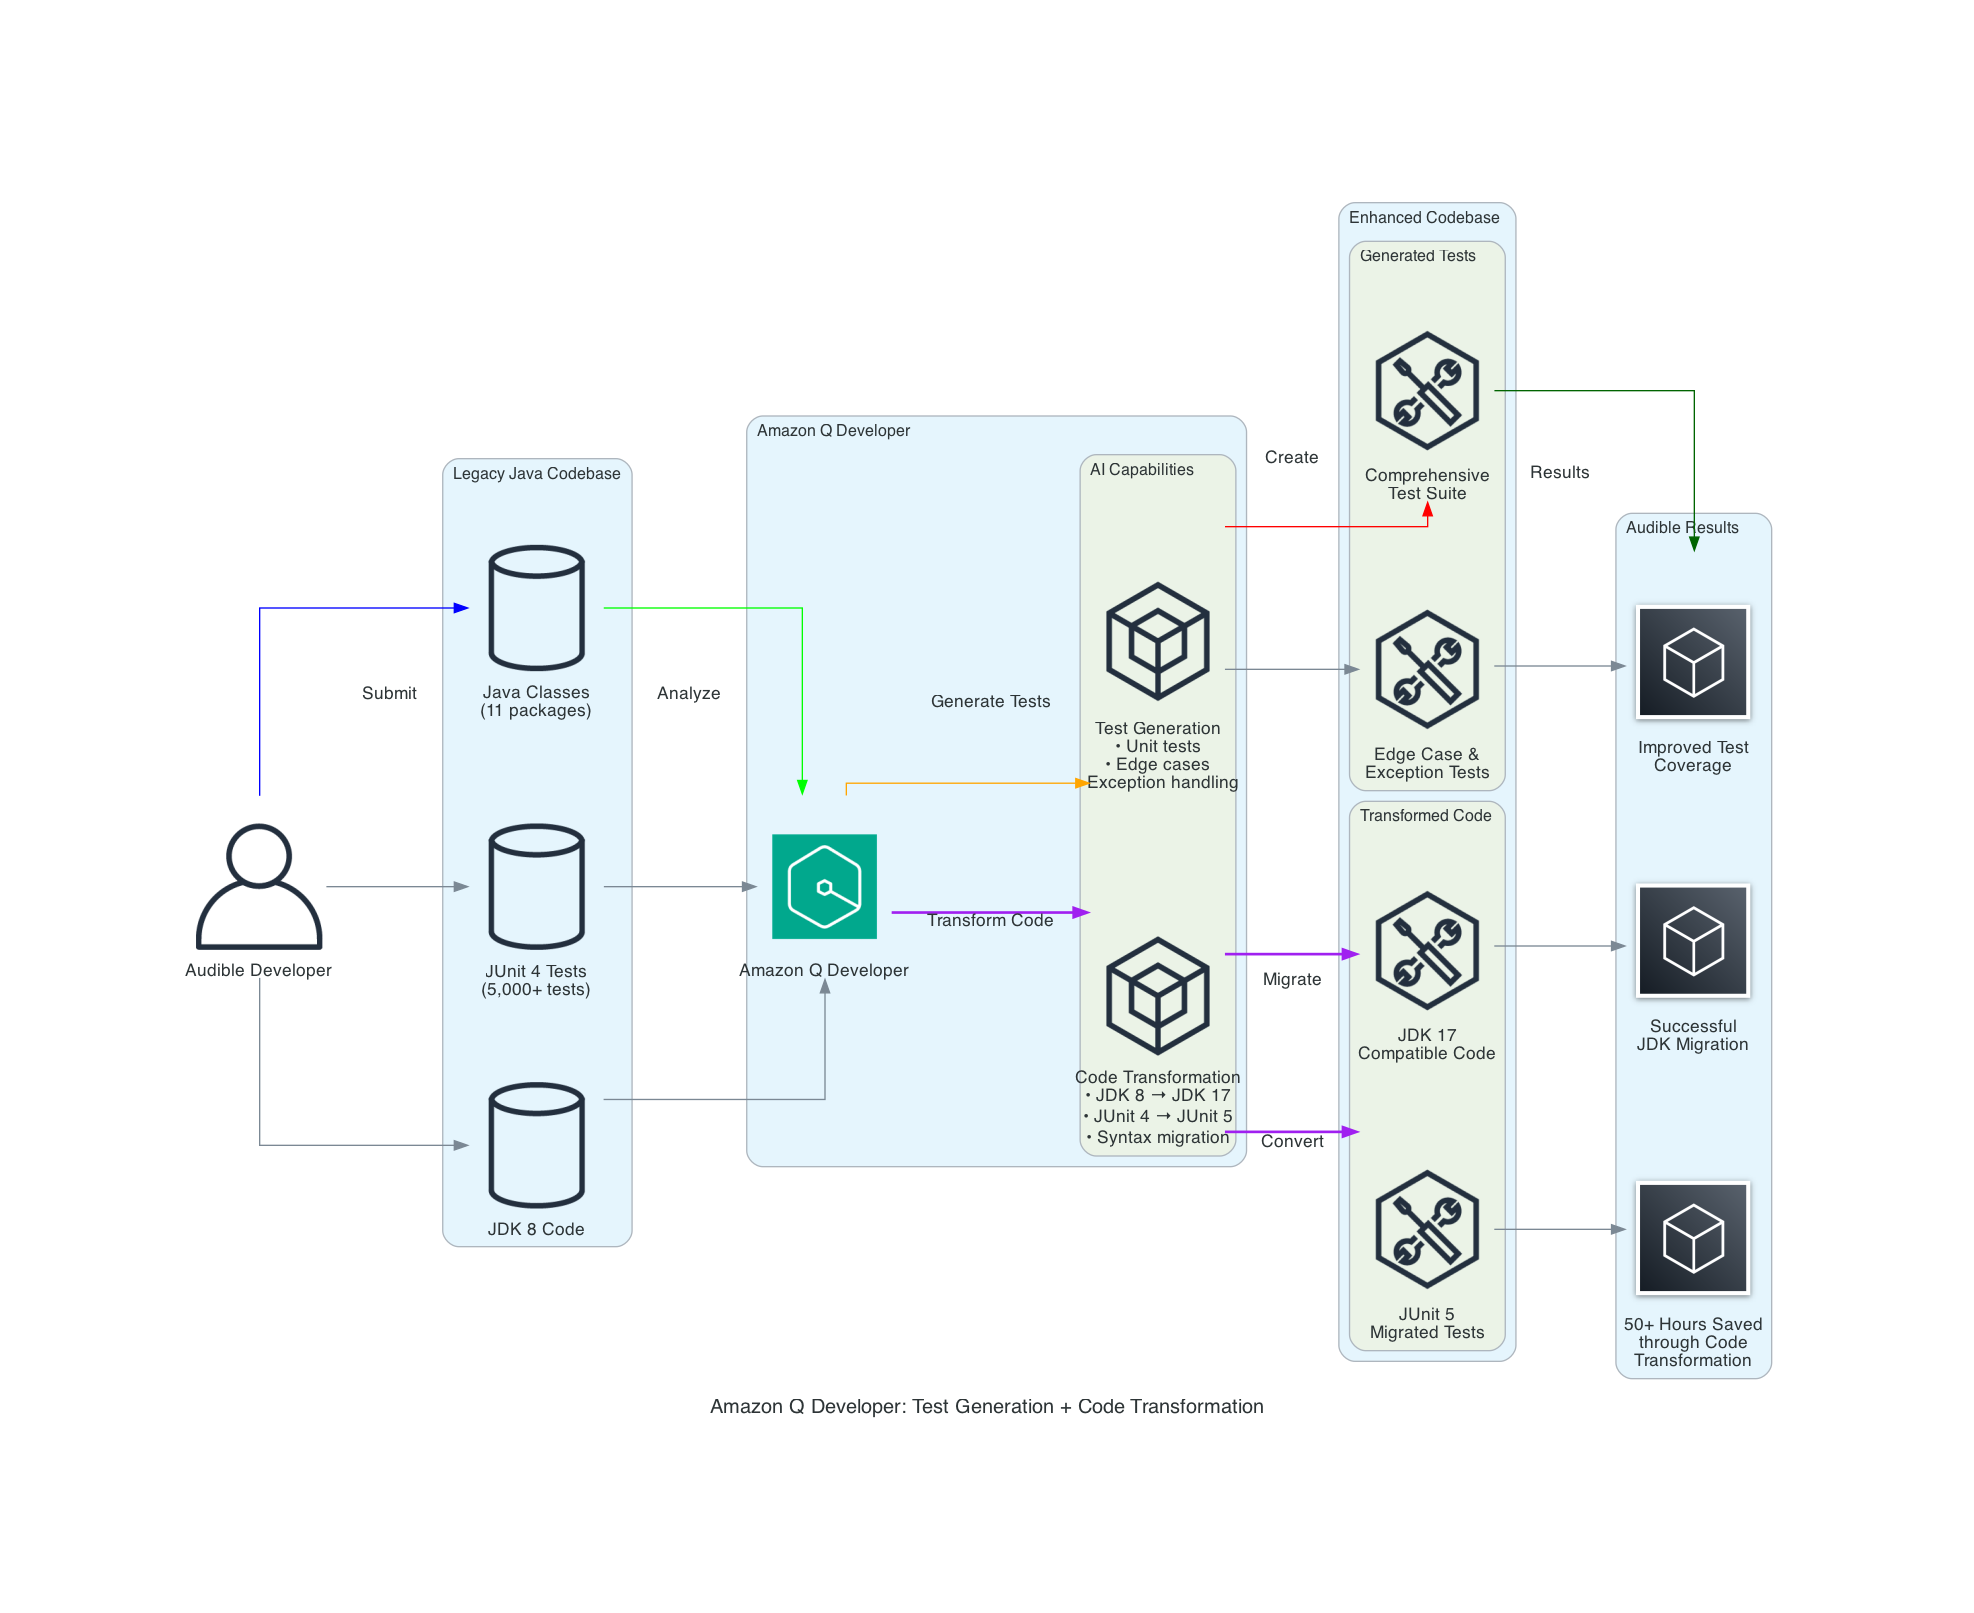
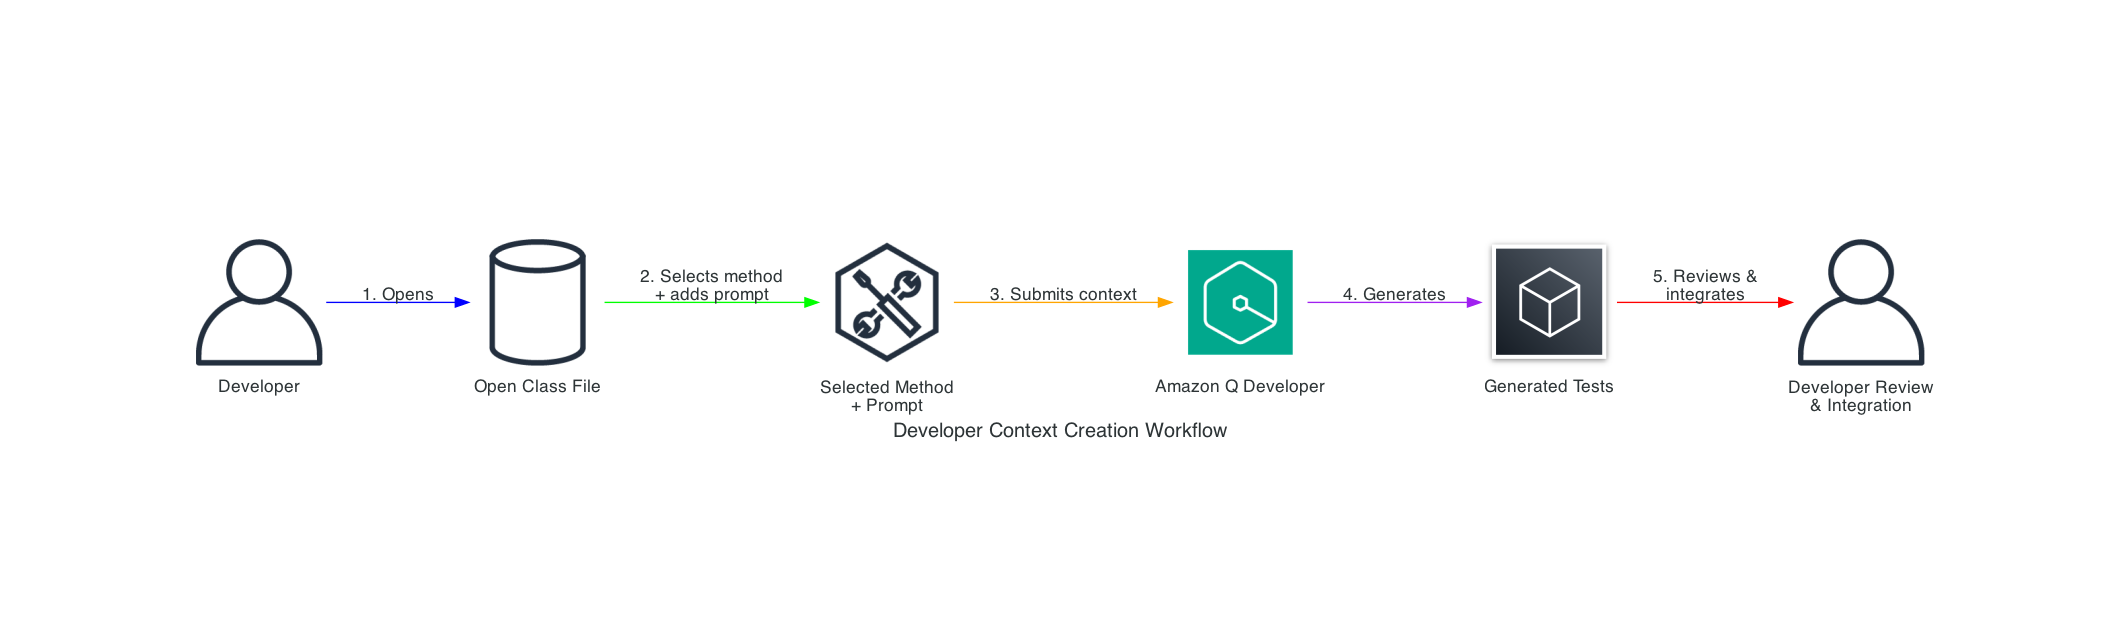

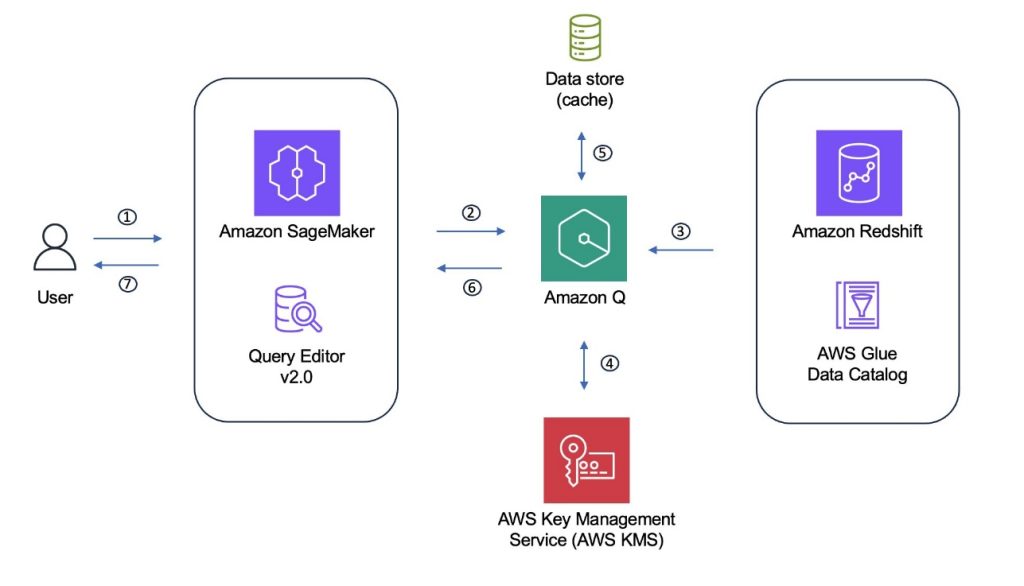
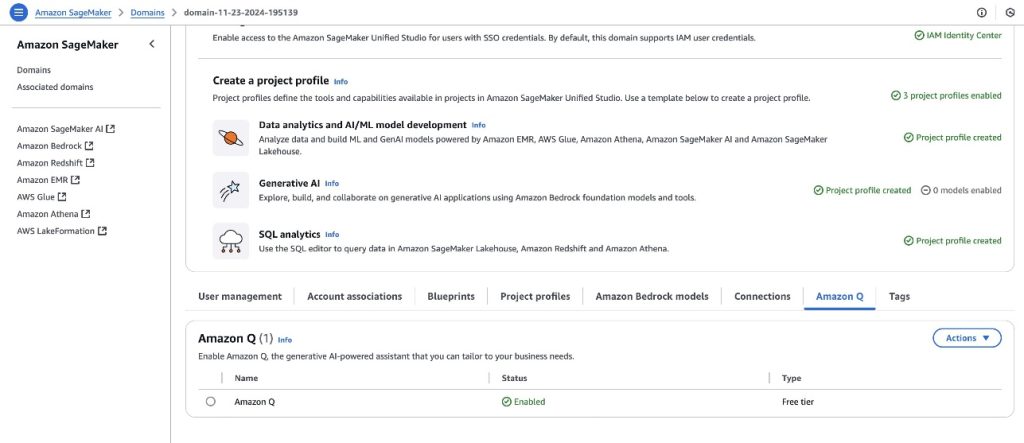
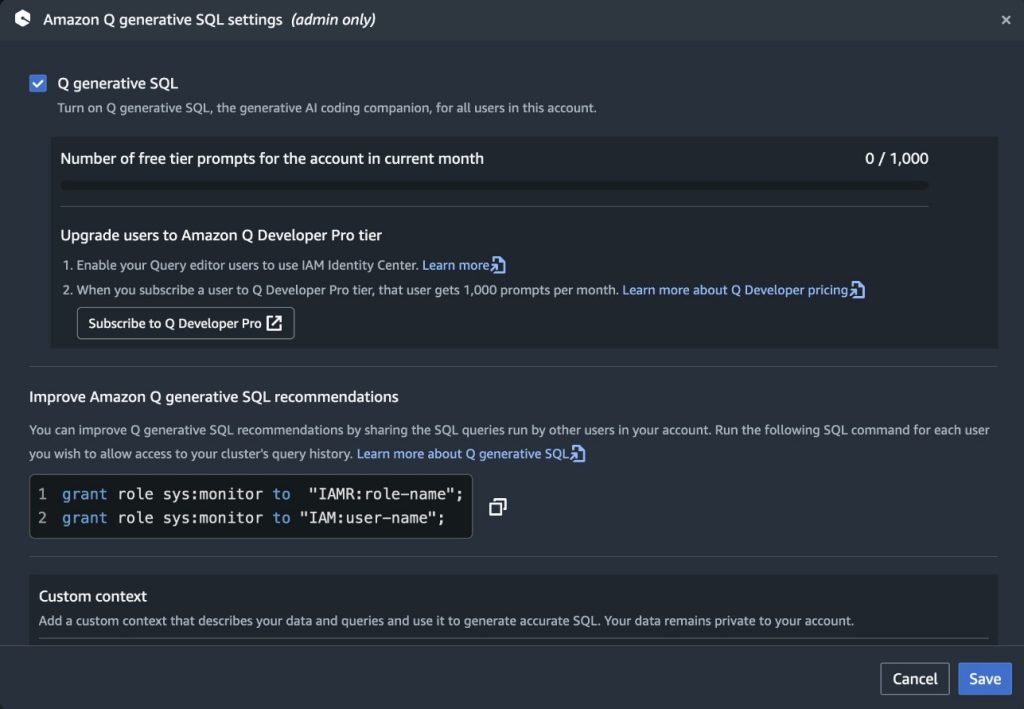
 Gregory Knowles is a data and AI specialist solution architect at AWS, focusing on the UK public sector. With extensive experience in cloud-based architectures, Greg guides public sector customers in implementing modern data solutions. His expertise spans governance, analytics, and AI/ML. Greg’s passion lies in accelerating transformation and innovation to improve productivity and outcomes. He has successfully led projects that moved data systems into the cloud, adopted new data architectures, and implemented AI at scale in production.
 Abhinav Tripathy is a Software Engineer and Security Guardian at AWS, where he develops Amazon Q generative SQL by combining machine learning, databases, and web systems. Abhinav is passionate about building scalable web systems from scratch that solve real customer challenges. Outside of work, he enjoys traveling, watching soccer, and playing badminton.
 Erol Murtezaoglu is a Technical Product Manager at AWS, is an inquisitive and enthusiastic thinker with a drive for self-improvement and learning. He has a strong and proven technical background in software development and architecture, balanced with a drive to deliver commercially successful products. Erol highly values the process of understanding customer needs and problems, in order to deliver solutions that exceed expectations.
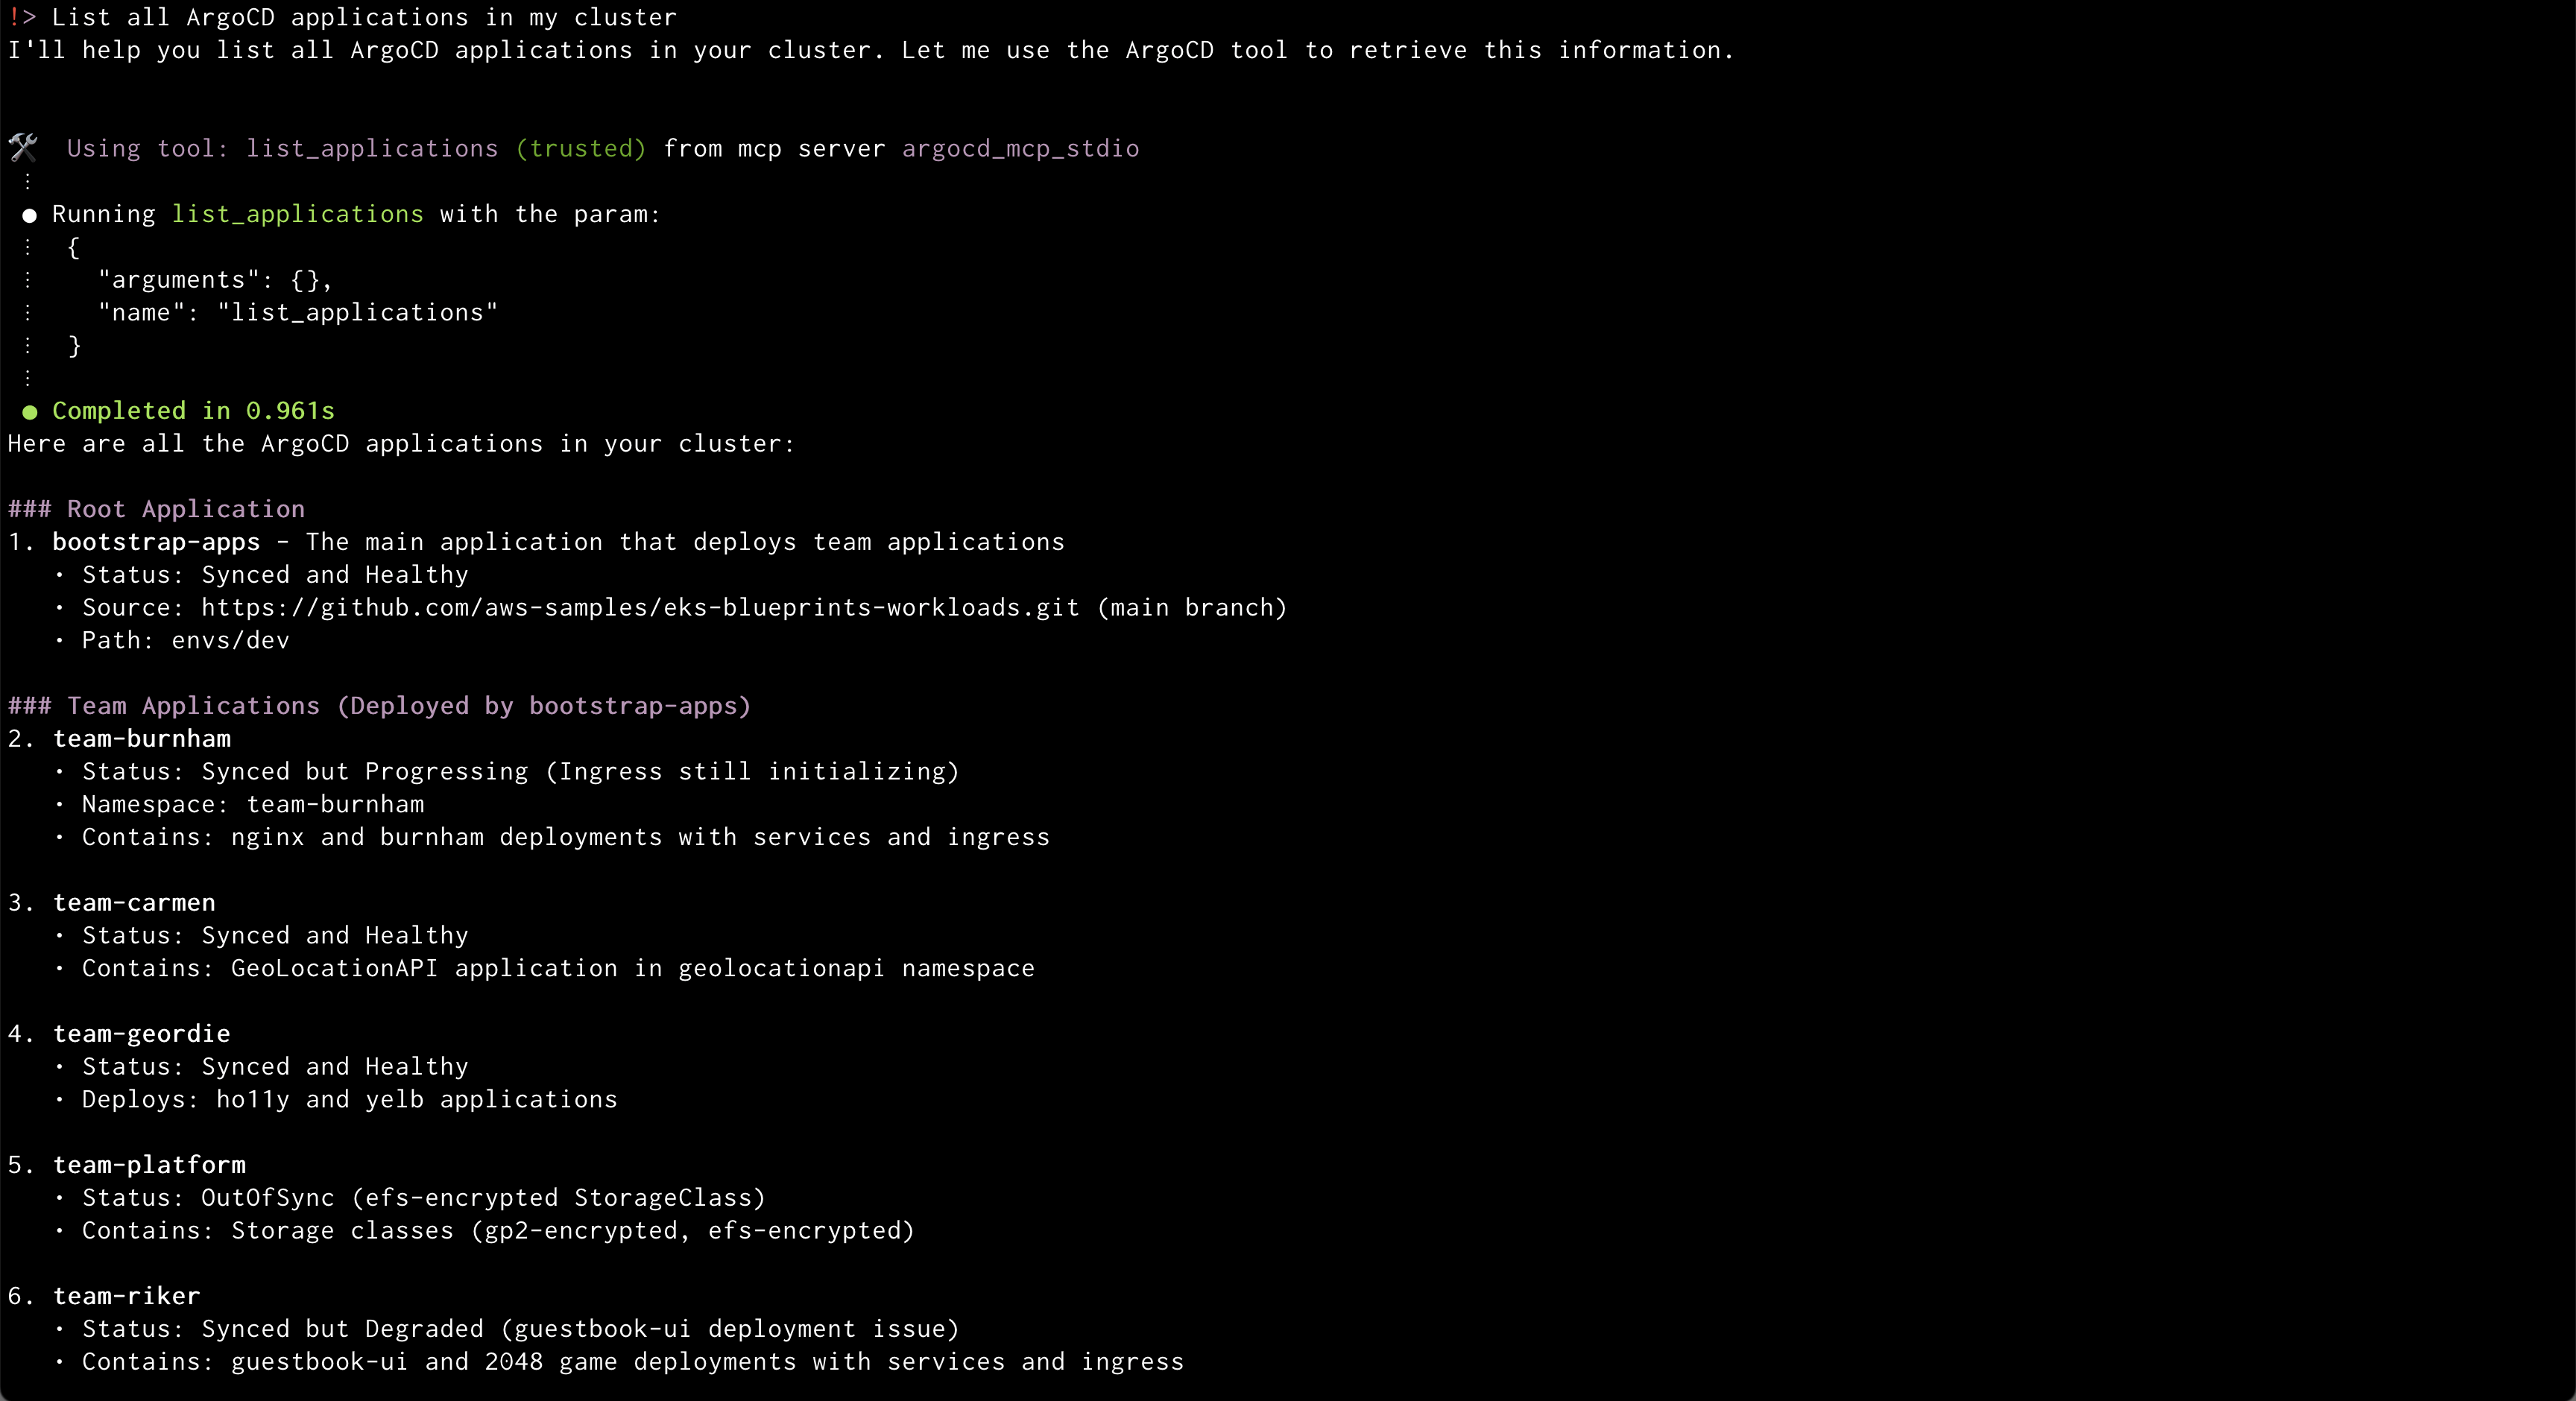 Amazon Q will use the ArgoCD MCP server to retrieve and display all applications
 Amazon Q will create a new application from GitRepo information provided
 Amazon Q will display the out of sync applications
 Amazon Q syncing application
 Amazon Q showing health status of all the resources in an application
 Amazon Q showing logs of problematic pod
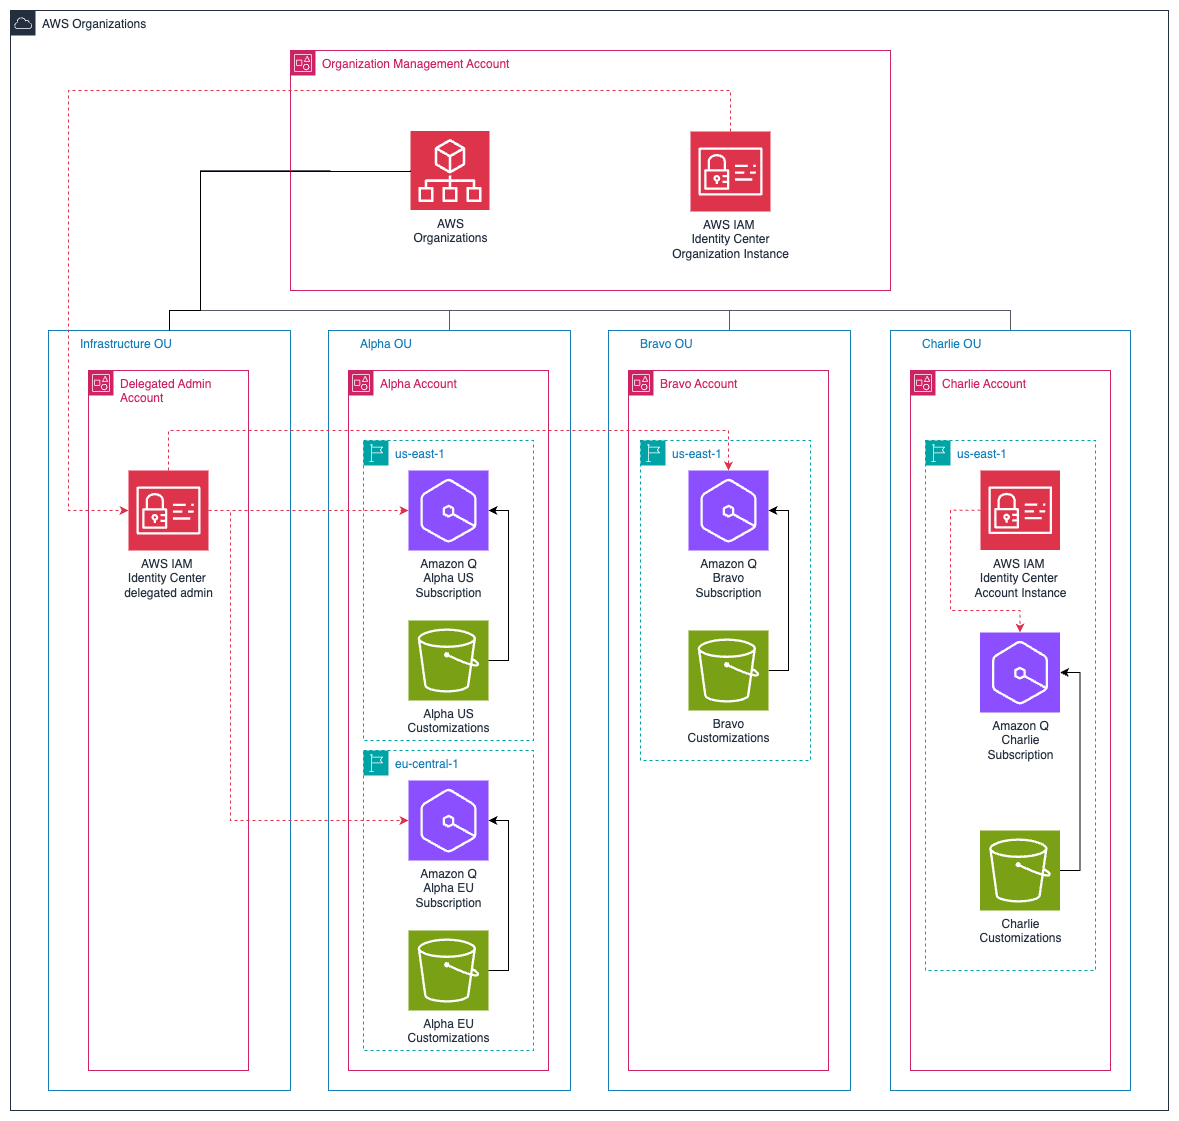
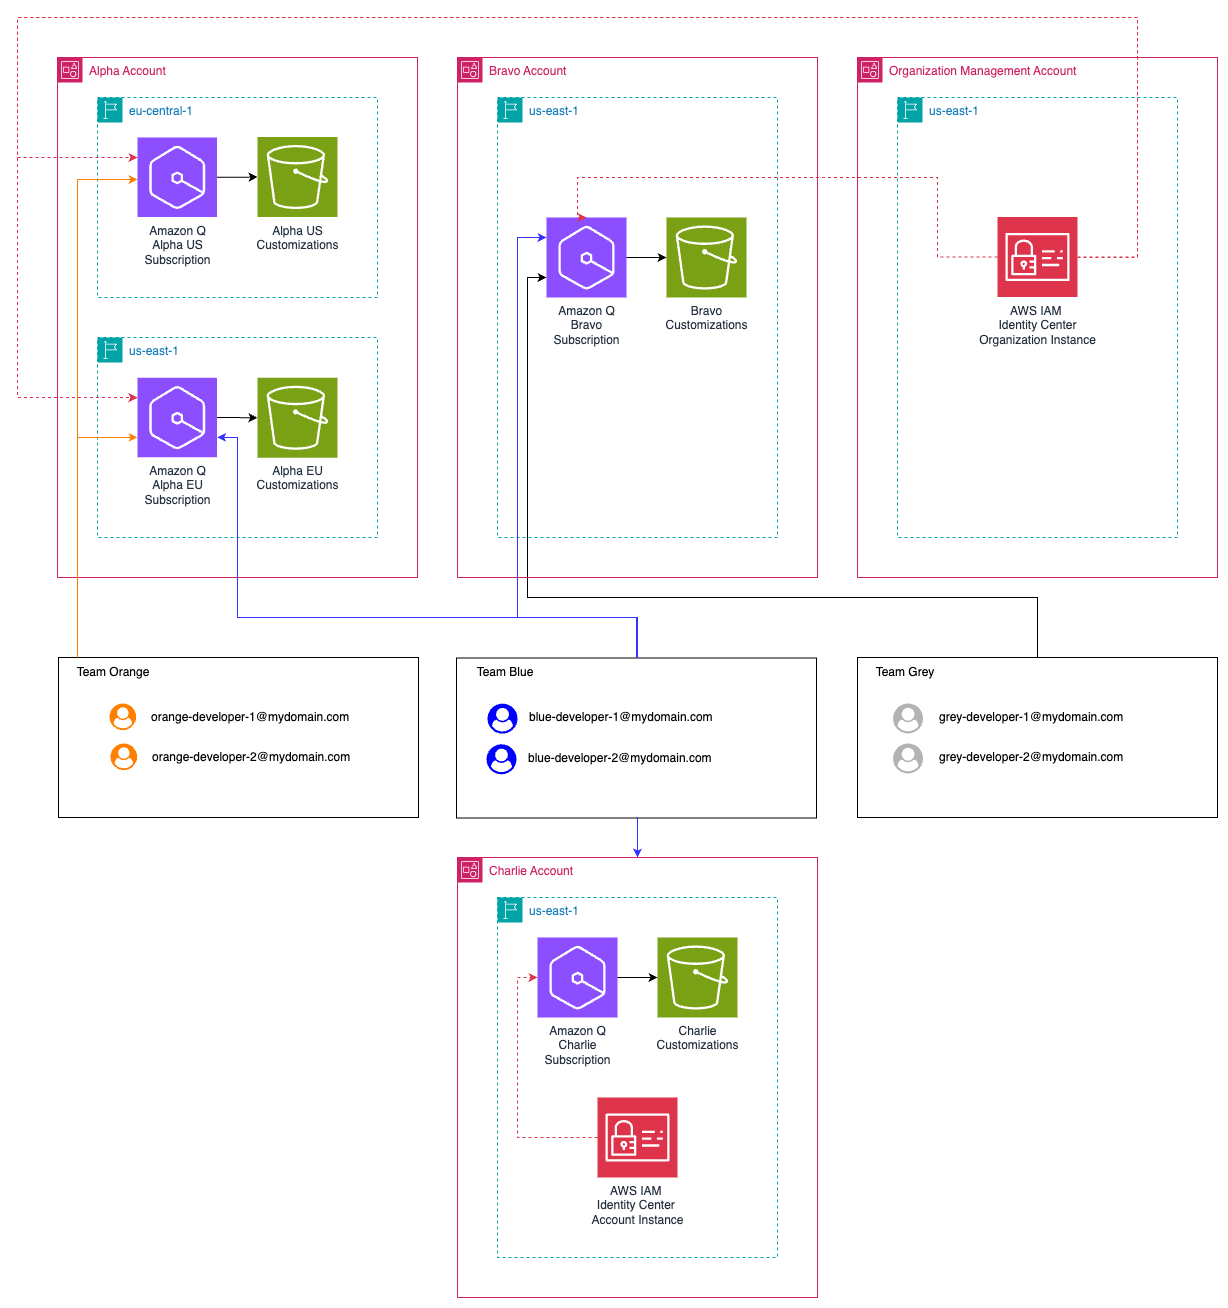
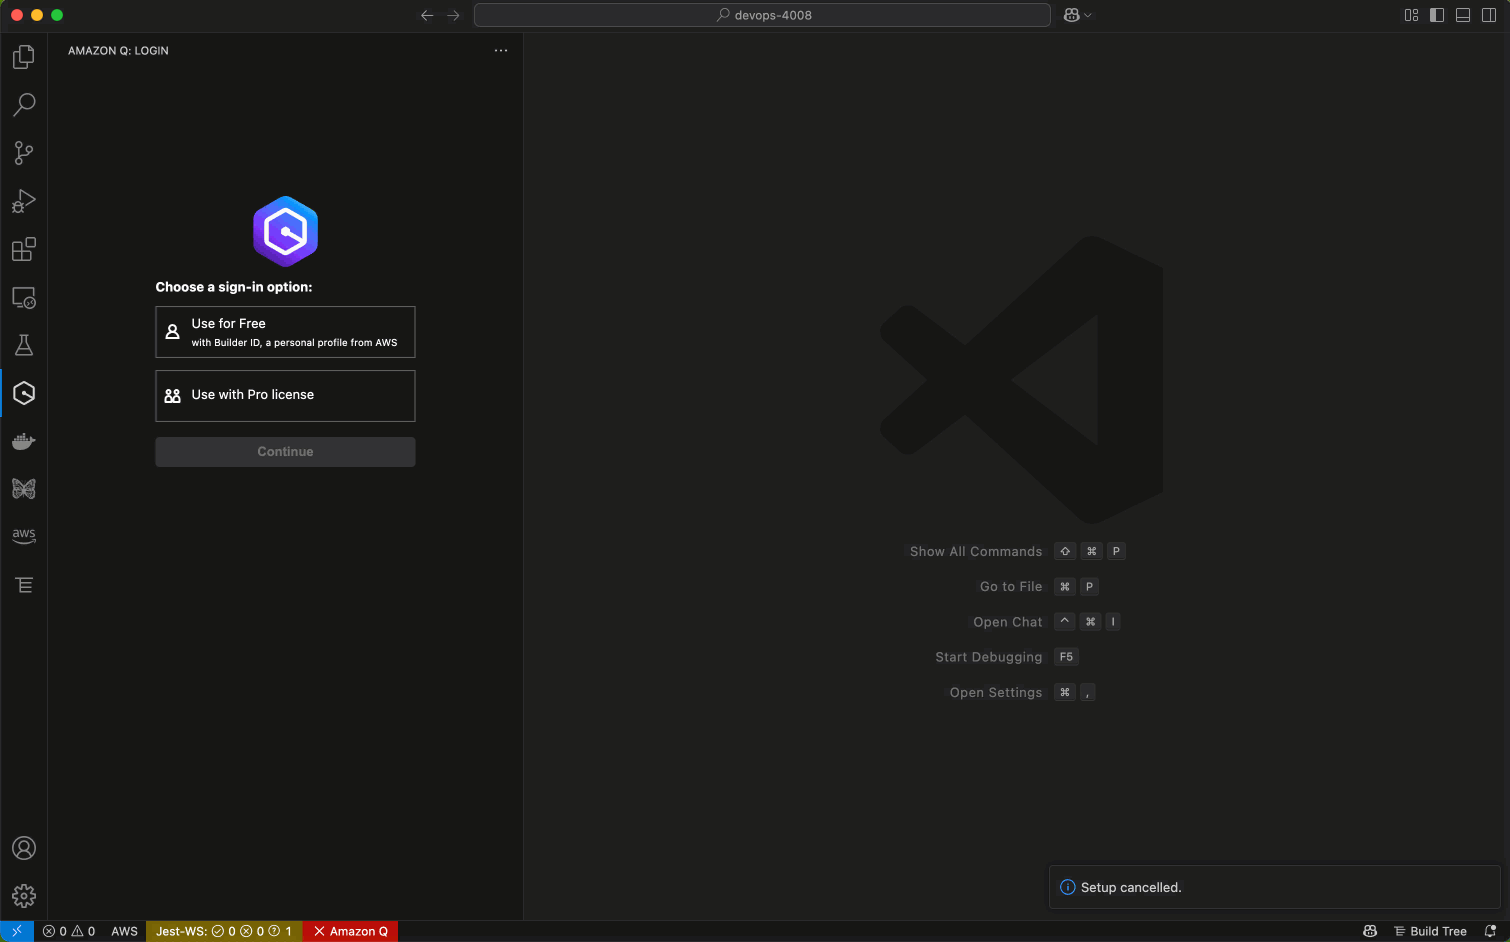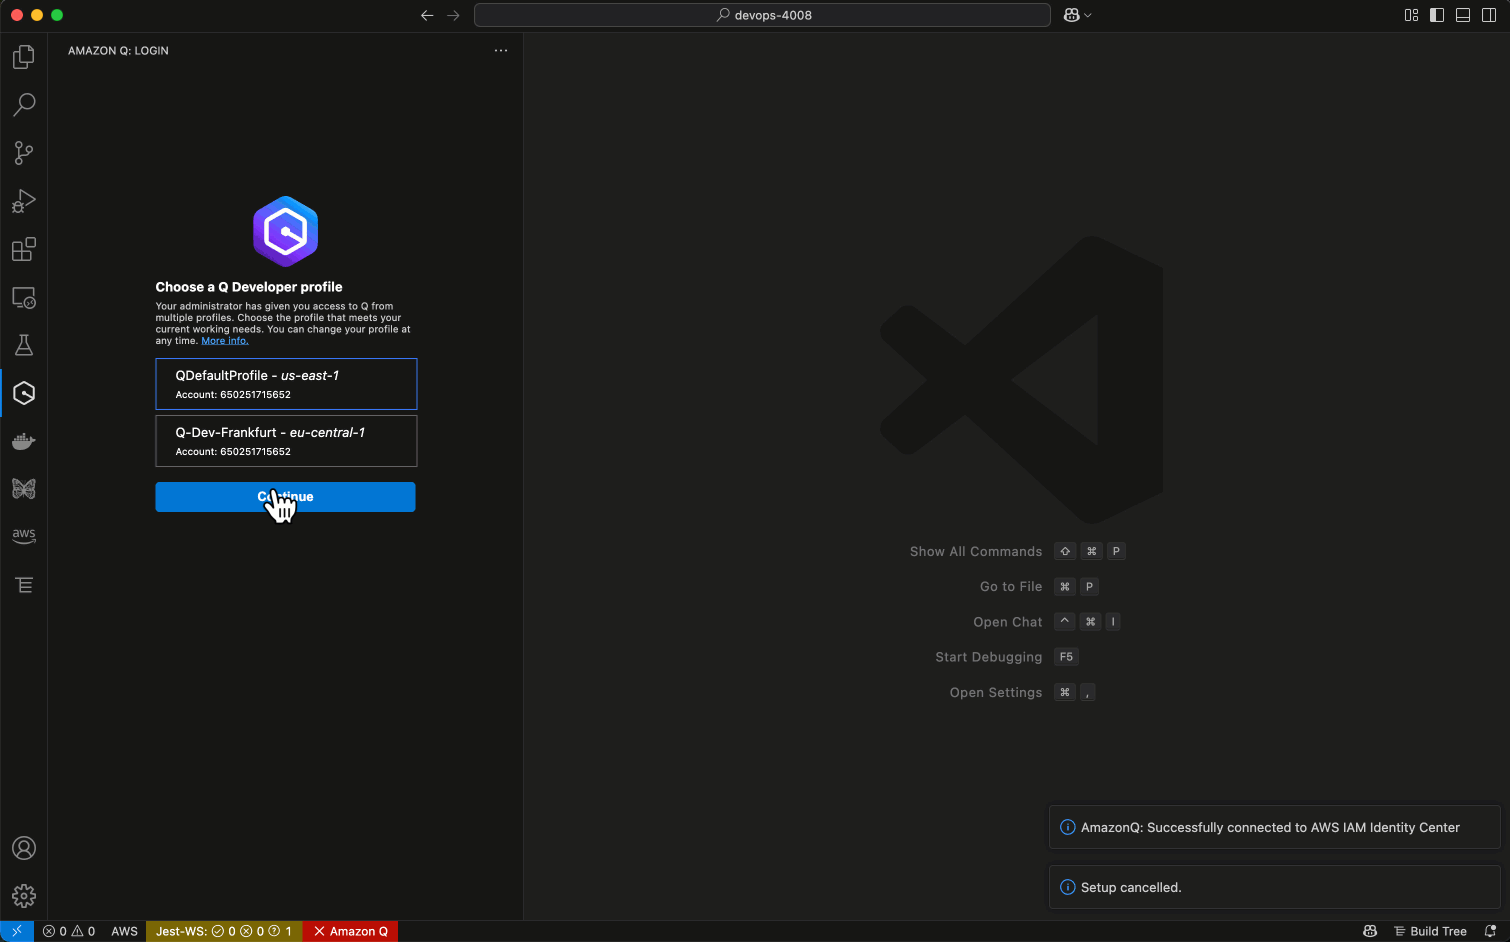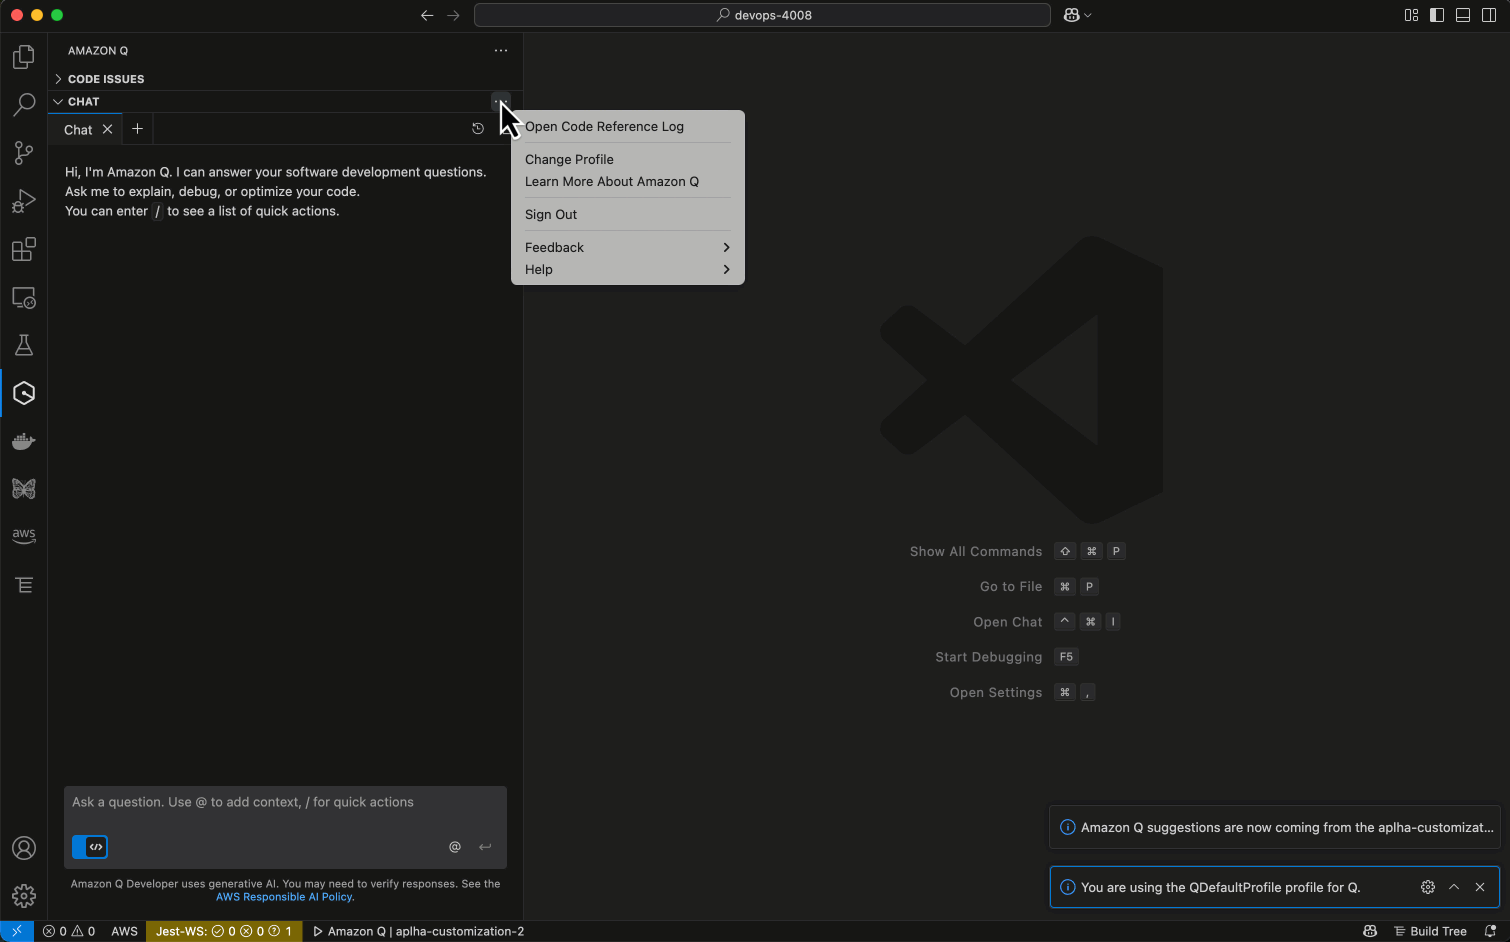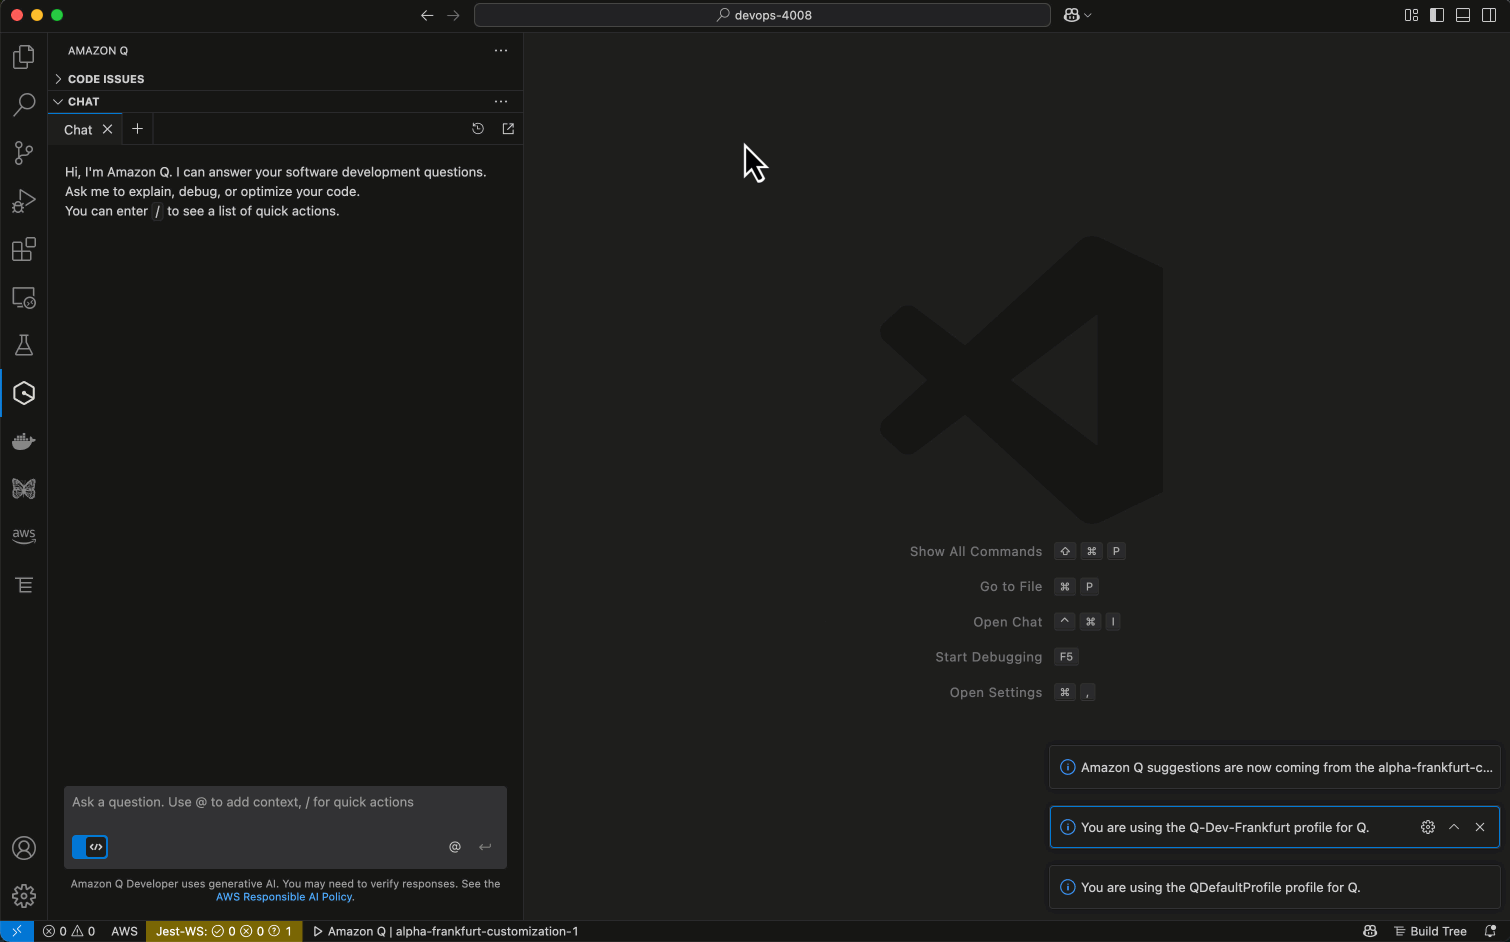
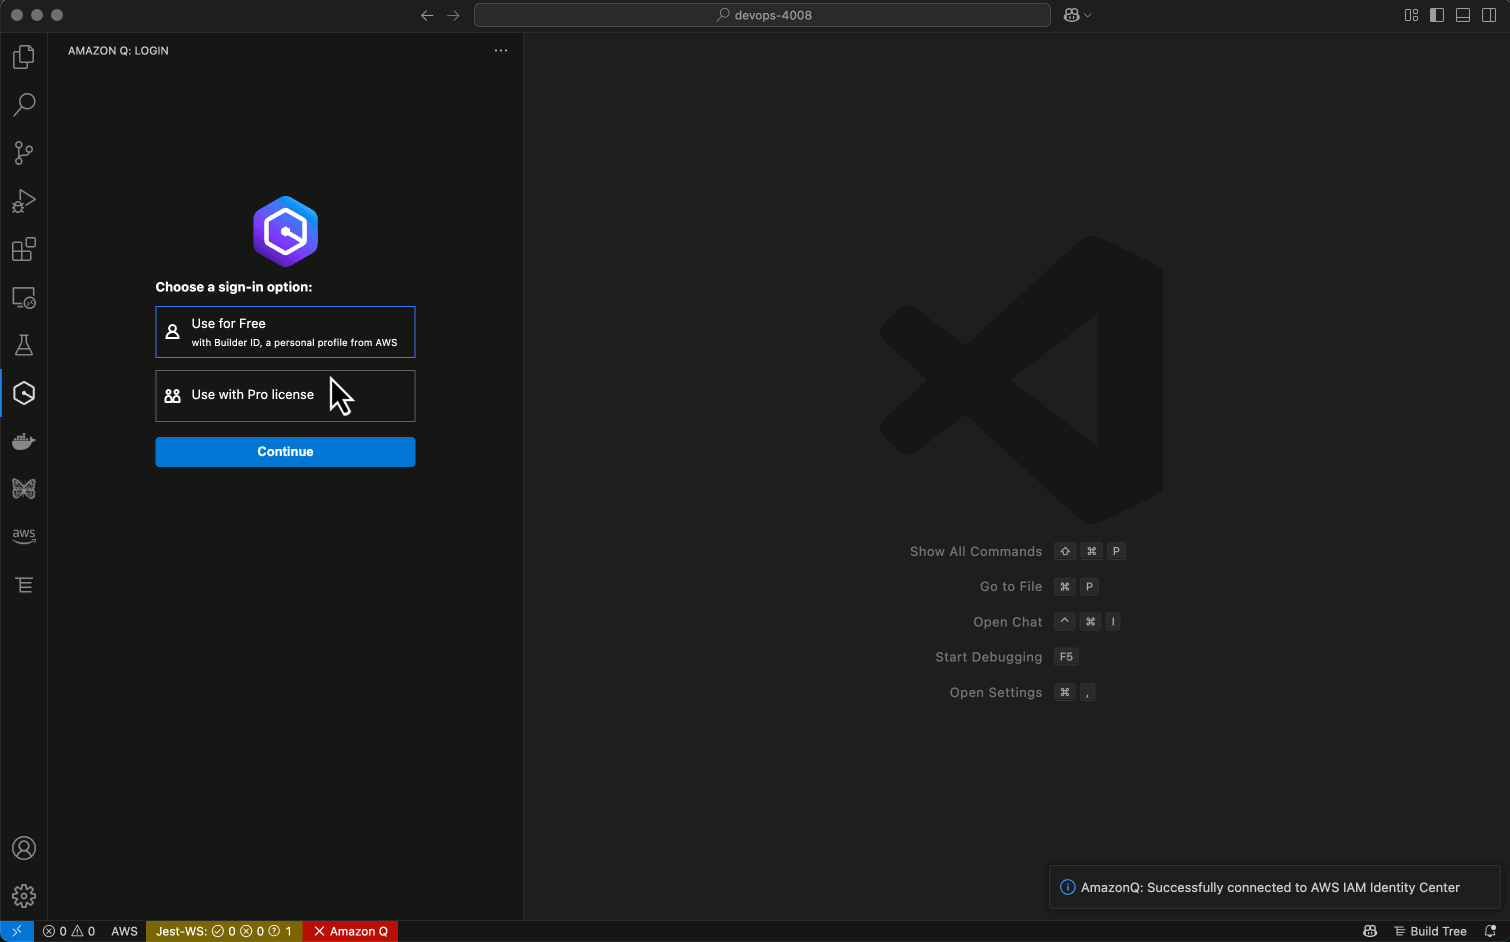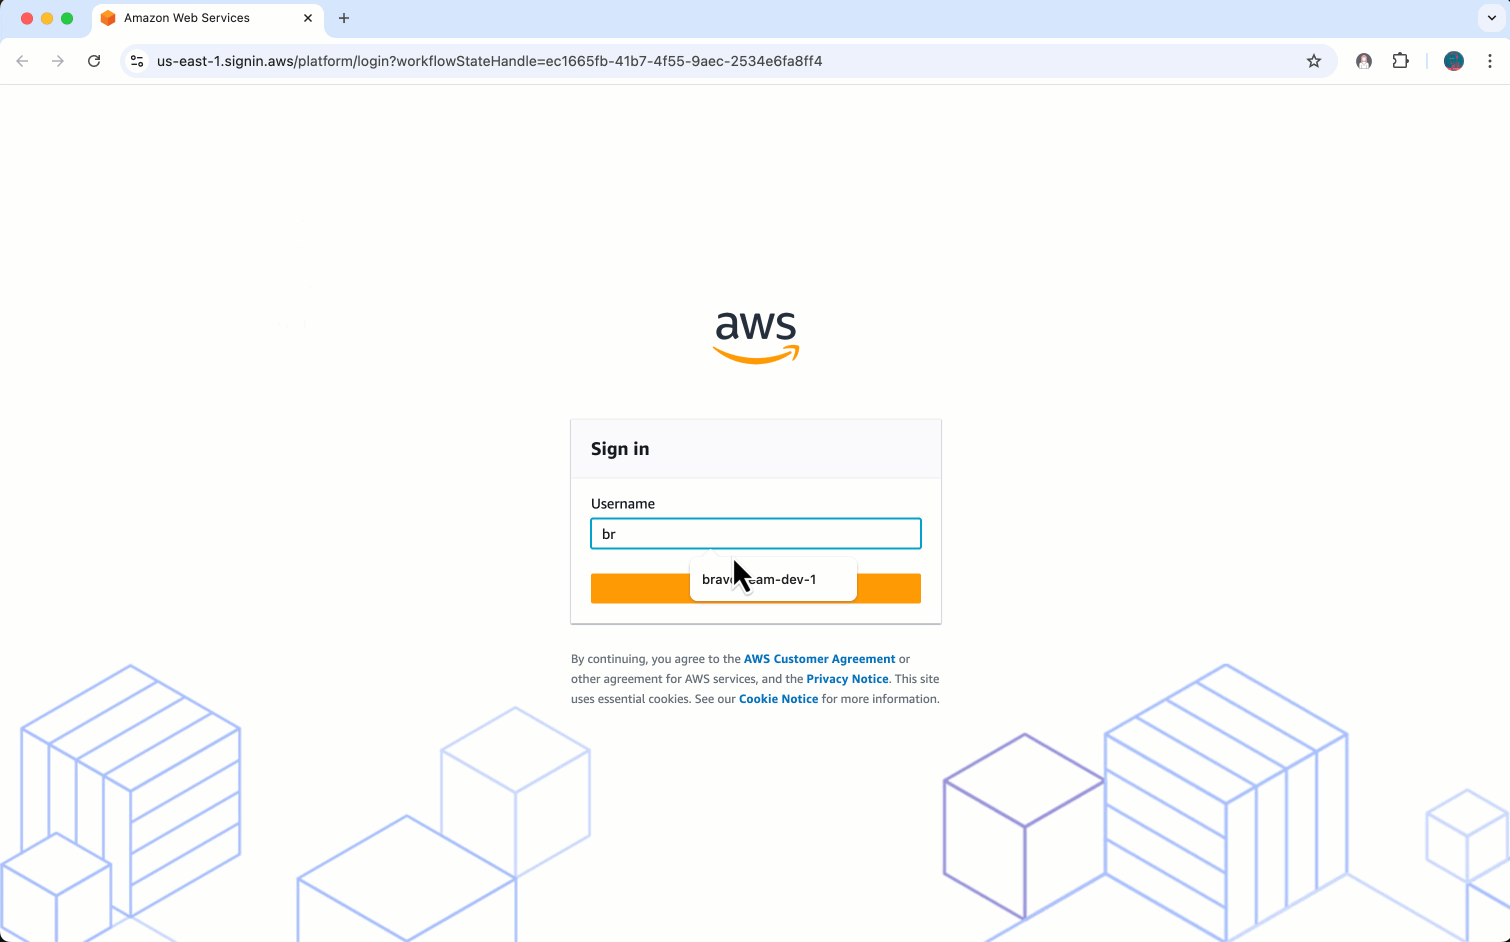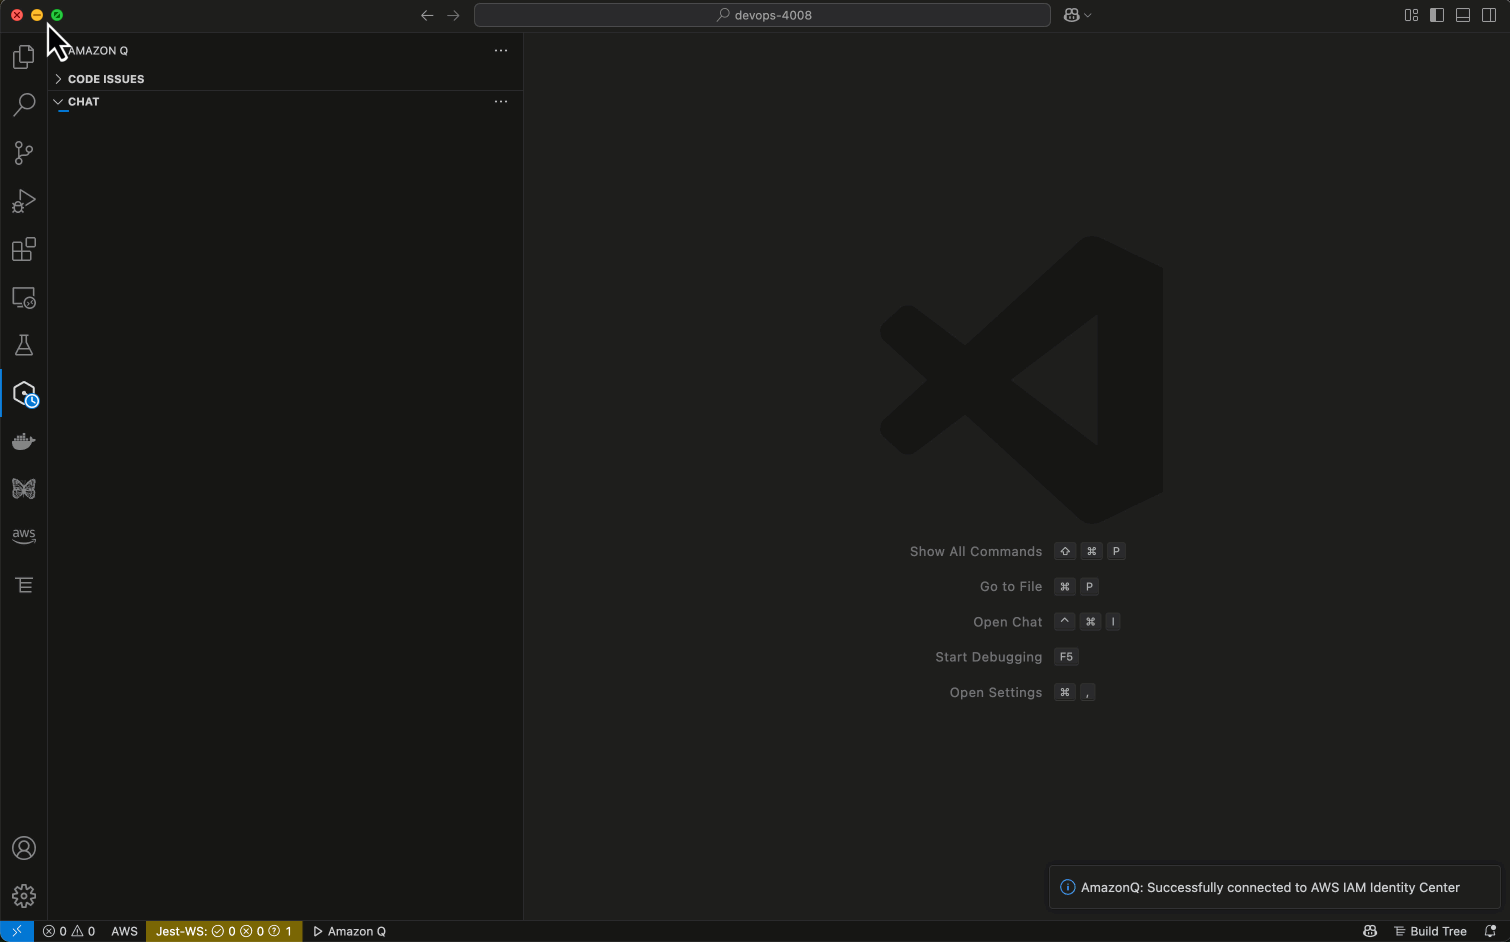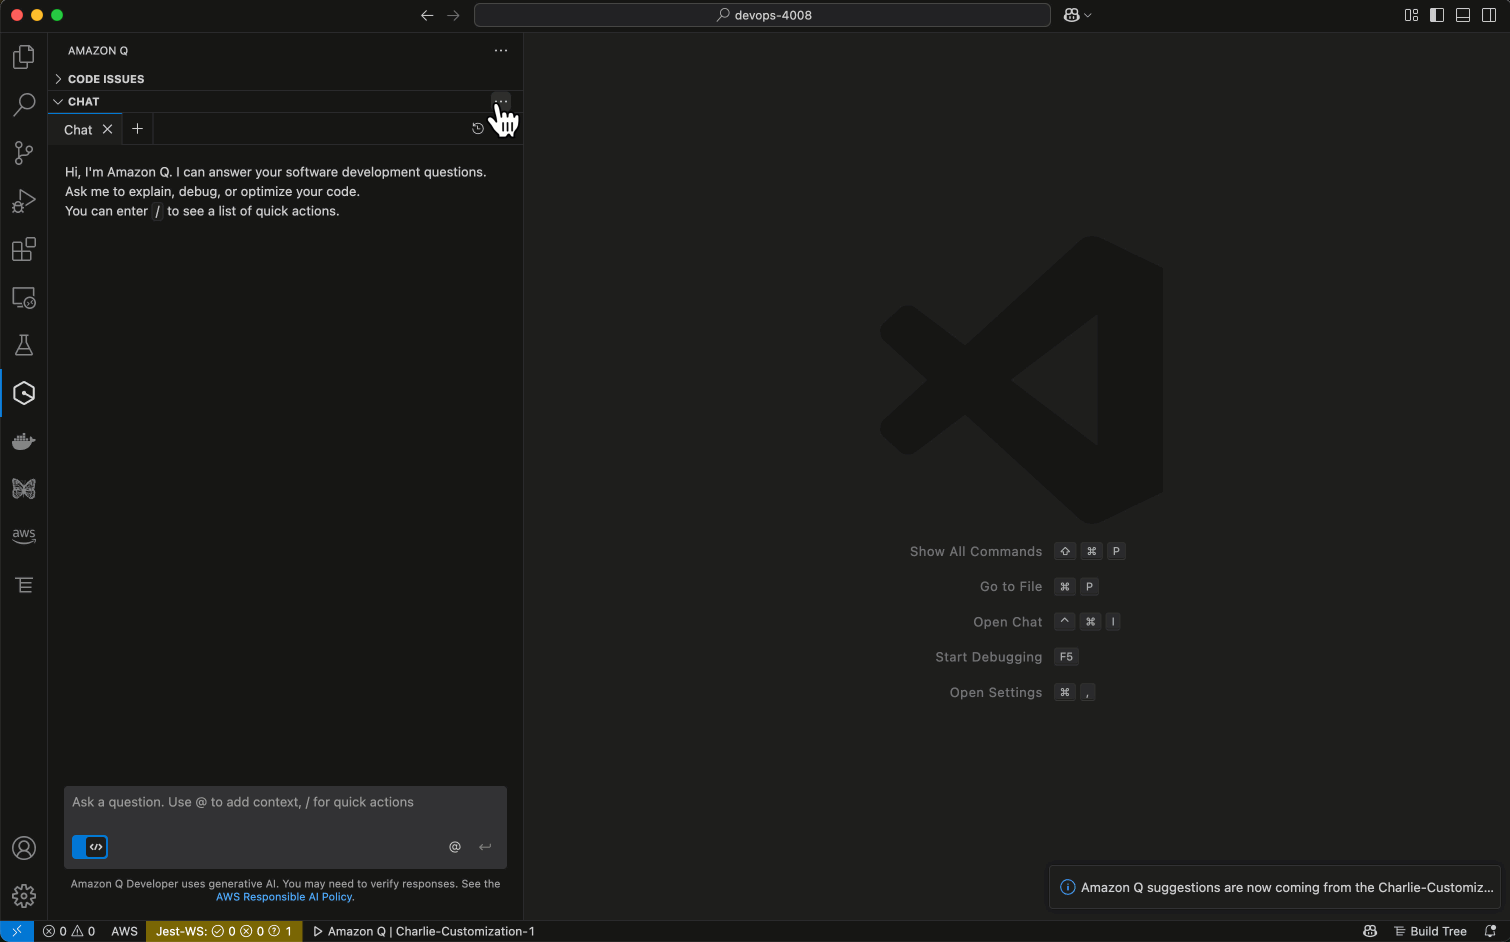

 Before continuing with this AWS Weekly Roundup, I’d like to share that last month I moved with my family to San Francisco, California, to start a new role as Developer Advocate/SDE, GenAI.


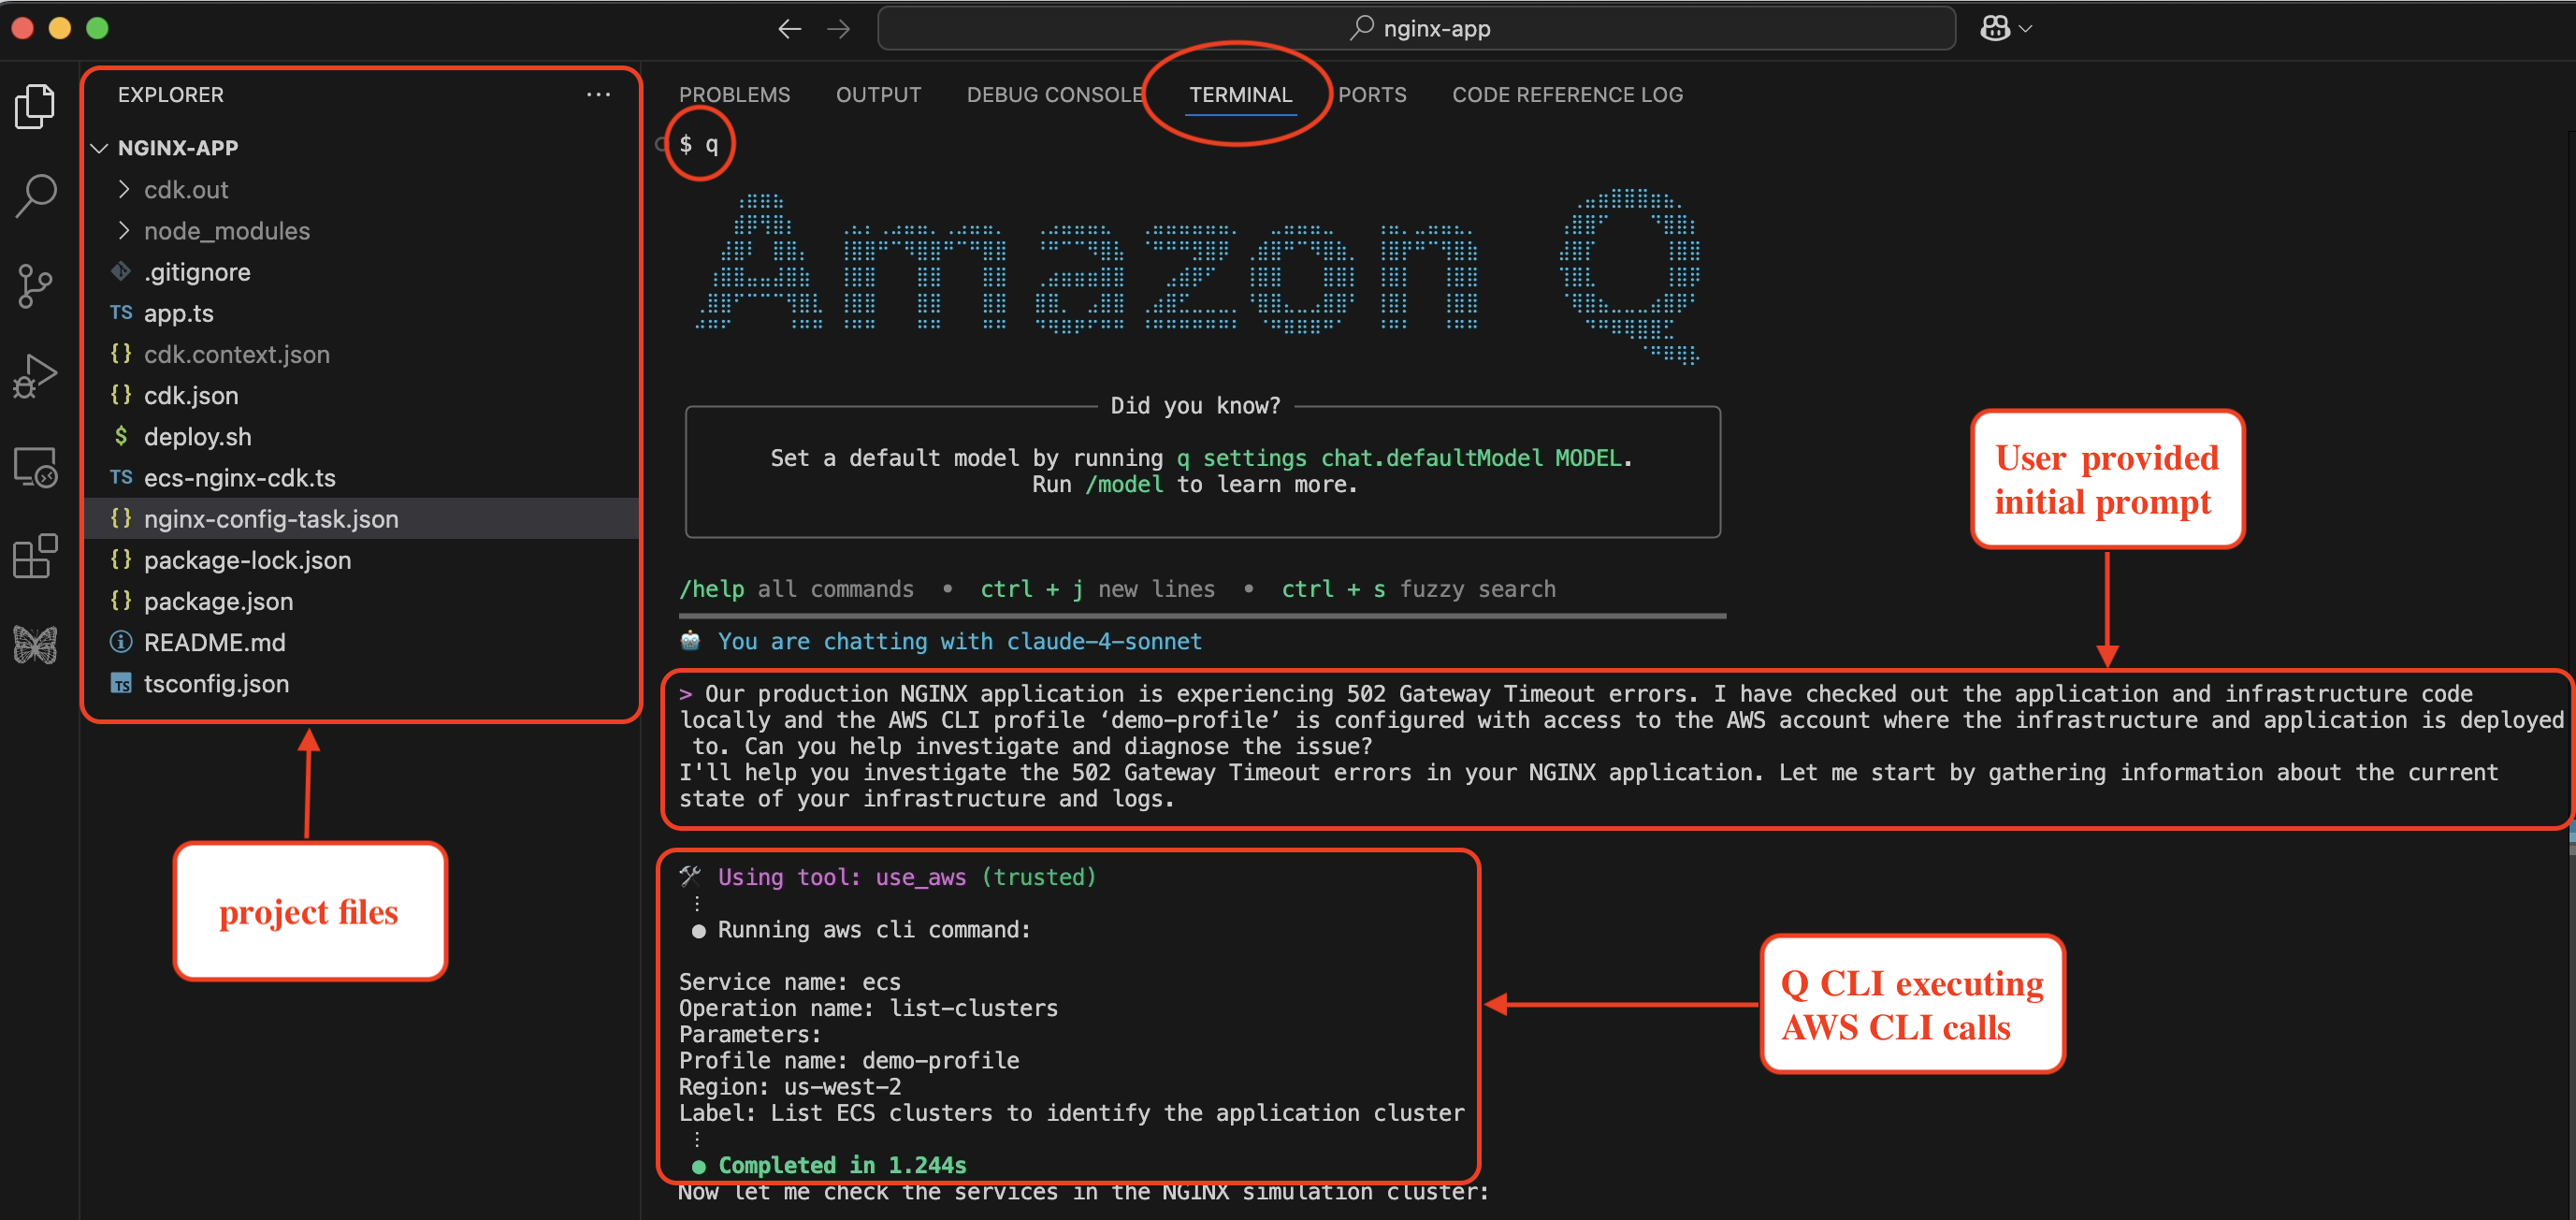


 Sid Vantair is a Solutions Architect with AWS covering Strategic accounts. He thrives on resolving complex technical issues to overcome customer hurdles. Outside of work, he cherishes spending time with his family and fostering inquisitiveness in his children.


