Tag Archives: java

Using the GitHub Copilot SDK for Java

Post Syndicated from Edward Burns original https://github.blog/engineering/using-the-github-copilot-sdk-for-java/


Java developers no longer have to rely on Java framework-specific approaches to drive AI from their enterprise apps.

While it is true that Langchain4j empowered developers by disintermediating specific AI vendors, you still had a dependency on Langchain4j. And with Spring AI, well, of course you had a dependency on design choices made by Spring, if not on Spring itself.

Now, GitHub Copilot SDK for Java is the first truly framework agnostic way to drive AI from Java. And with its BYOK support, GitHub Copilot SDK for Java is also AI vendor neutral.

💡 Even though it’s called GitHub Copilot SDK, you can use it with any direct model provider, such as OpenAI, Azure, Anthropic, or OpenAI-compatible endpoints, by passing a provider/ProviderConfig with your own baseUrl + apiKey (or bearer token). No Copilot subscription required.

The GitHub Copilot SDK for Java is a client library that empowers your server-side Java code to create Copilot agent sessions, register tools, send prompts, and receive structured responses—all programmatically. It works in server environments, including Jakarta EE and Spring. If you’ve been building enterprise Java for any length of time, this SDK will feel like home: CompletableFuture, annotations, lambdas, virtual threads, it’s all here.

This post shows you how to use the SDK, walks through a complete Jakarta EE 11 sample application, and leaves you with concrete next steps to try it yourself. I chose Jakarta EE 11 for my demo because I was the lead release coordinator for that release. I believe in open standards as the best way to empower developers. For more on Jakarta EE 11 see this InfoQ article.

This sample app is an agent harness using Jakarta EE 11. But, of course, developers can build their own agent harness using the well-known Java frameworks and libraries of their choice.

Clone the sample app and try it yourself >

Where to get it

The SDK is available as a Maven dependency:

<dependency>
    <groupId>com.github</groupId>
    <artifactId>copilot-sdk-java</artifactId>
    <version>1.0.7-preview.1</version>
</dependency>

Prerequisites:

  • JDK 17 or 25 (25 recommended — unlocks virtual threads and other modern features)
  • Maven 3.9+
  • A GitHub account with an active Copilot subscription
  • The Copilot CLI installed locally at version 1.0.71 or later.

Walk through the sample app

The best way to see the SDK in action is to run this sample application.

Get the code

git clone https://github.com/microsoft/Build26-BRK206-your-agent-anywhere-multiclient-multidevice-with-github-copilot-sdk.git
cd Build26-BRK206-your-agent-anywhere-multiclient-multidevice-with-github-copilot-sdk/src/java-agent-orchestrator
mvn clean package liberty:run
# Open http://localhost:9080/index.xhtml

The Java demo is built on:

Concern Technology
Runtime Open Liberty 26.0.0.5
Platform Jakarta EE 11 (Faces 4.1, CDI 4.1, WebSocket 2.2, Data 1.0, Persistence 3.2)
UI PrimeFaces 15.0.16
AI orchestration Copilot SDK for Java 1.0.7-preview.1
Database H2 in-memory (10 seed property listings)

What the app does

The application is a real-estate lead-management agent pipeline. A customer submits an enquiry (“I’m looking for a 3-bedroom house in London under £800,000”), and the system spins up an isolated Copilot Agent on a virtual thread to process it through a pipeline:
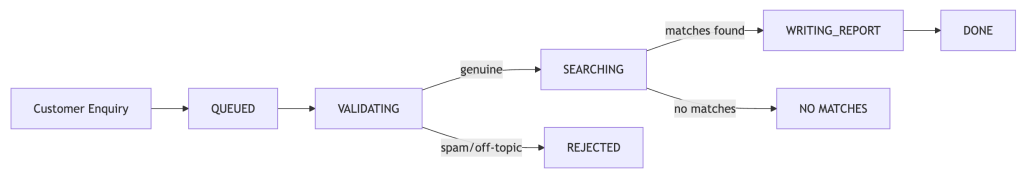
Application flow diagram showing the pipeline stages: Customer Enquiry flows to QUEUED, then VALIDATING, which branches to either SEARCHING (if genuine) or REJECTED (if spam/off-topic). SEARCHING leads to WRITING_REPORT (if matches found) or NO MATCHES. WRITING_REPORT completes at DONE.

The architecture uses Jakarta WebSocket to push real-time status updates from the server to the browser, so you can watch agents progress through phases as the model calls tools:
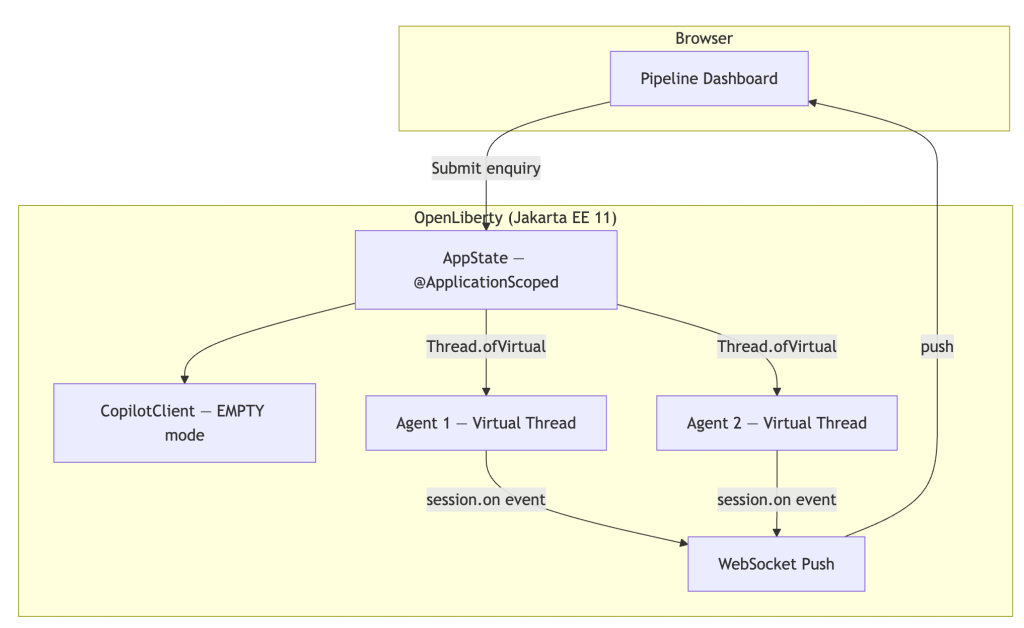
Application architecture diagram showing Browser with Pipeline Dashboard connecting to Open Liberty server containing AppState, CopilotClient in EMPTY mode, virtual thread agents, and WebSocket push for real-time UI updates.

Submit multiple inquiries simultaneously to see concurrent virtual-thread agents in action. Each one processes independently with its own Copilot session.
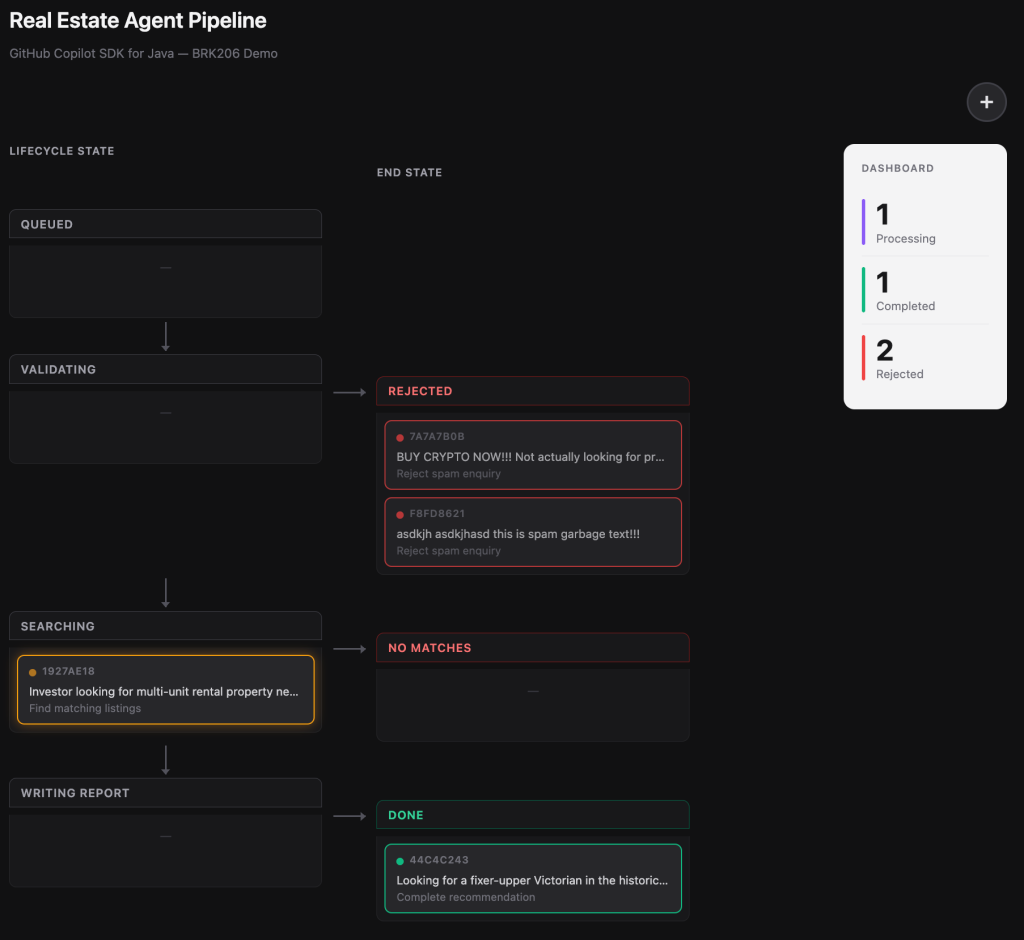
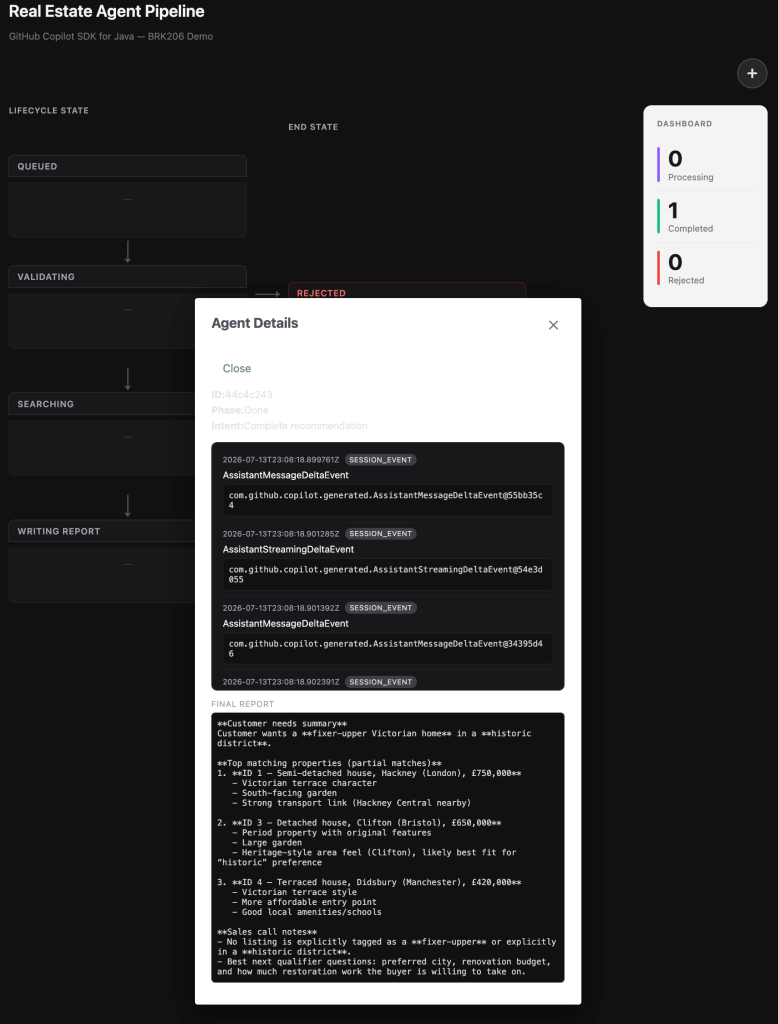
Screenshot of the sample application showing the pipeline dashboard with multiple enquiries being processed concurrently.
Screenshot of the sample application showing detailed agent event log and property search results.

SDK features in action

Let’s walk through the key SDK features as they appear in the sample code.

Defining tools with @CopilotTool

This is the headline API. If you’ve ever written a @GET endpoint in JAX-RS or an @MessageDriven bean, this will feel instantly familiar:

@CopilotTool(value = "Sets the current phase of the agent. Use this to report progress.",
             name = "set_current_phase")
public String setCurrentPhase(
        @CopilotToolParam("The phase to transition to (VALIDATING, SEARCHING, "
                + "WRITING_REPORT, REJECTED_GARBAGE, REJECTED_NO_MATCHES, or DONE)")
        String phaseName) {
    phase = Phase.valueOf(phaseName.trim().toUpperCase(Locale.ROOT));
    notifyUi();
    return "Phase set to " + phase.getLabel();
}

The @CopilotTool annotation declares the method as a tool the model can call. The @CopilotToolParam annotation describes each parameter so the model knows what to pass. The SDK handles all the JSON Schema generation, argument parsing, and dispatch. You just write a normal Java method.

Two build prerequisites for @CopilotTool. The annotation-based tool API is currently an experimental feature of the SDK, so you need to configure two things in your Maven build:

  1. Enable experimental APIs: pass -Acopilot.experimental.allowed=true to the compiler. Without this flag, the annotation processor will refuse to generate the tool metadata. For more details on the experimental APIs see Copilot SDK documentation.
  2. Register the annotation processor: add the SDK as an annotationProcessorPath so the compiler can find the @CopilotTool processor and generate the $$CopilotToolMeta classes at compile time.

Both are configured in the maven-compiler-plugin:

<plugin>
    <groupId>org.apache.maven.plugins</groupId>
    <artifactId>maven-compiler-plugin</artifactId>
    <version>3.15.0</version>
    <configuration>
        <compilerArgs>
            <arg>-Acopilot.experimental.allowed=true</arg>
        </compilerArgs>
        <annotationProcessorPaths>
            <path>
                <groupId>com.github</groupId>
                <artifactId>copilot-sdk-java</artifactId>
                <version>1.0.7-preview.1</version>
            </path>
        </annotationProcessorPaths>
    </configuration>
</plugin>

To register all annotated tools from an object:

List<ToolDefinition> annotatedTools = ToolDefinition.fromObject(this);

Inline lambda tools with ToolDefinition.from(...)

When you want a tool defined at the call site without a dedicated method, use the lambda style:

ToolDefinition reportIntentTool = ToolDefinition
        .from("report_intent",
              "Reports the current intent of the agent",
              Param.of(String.class, "intent", "Intent in max 4 words"),
              (String intent) -> {
                  currentIntent = intent;
                  addEvent(Instant.now(), "intent", "Intent updated", intent);
                  notifyUi();
                  return "ok";
              })
        .overridesBuiltInTool(true);

Notice .overridesBuiltInTool(true). This tells the SDK that our report_intent tool deliberately replaces a built-in tool of the same name. This is useful when you need custom behaviour for a tool the model already knows about.

Cross-class tool scanning

Tools don’t have to live in the same class as your agent logic. Here’s searchProperties defined in a separate CDI bean:

@ApplicationScoped
public class PropertyDatabase {

    @CopilotTool(value = "Searches the real estate listings database. "
                       + "Returns up to 10 matching properties.",
                 name = "search_properties")
    public List<Property> searchProperties(
            @CopilotToolParam("Property type substring (e.g. 'flat', 'house')") String type,
            @CopilotToolParam("City substring (e.g. 'London', 'Bristol')") String city,
            @CopilotToolParam("Minimum number of bedrooms (0 for no minimum)") int minBedrooms,
            @CopilotToolParam("Maximum price in GBP (0 for no maximum)") double maxPriceGbp) {
        // ... filter and return matching properties ...
    }
}

You would normally register these with ToolDefinition.fromObject(propertyDatabase). In the sample app, we use a lambda wrapper instead, because CDI client proxies can obscure the annotation metadata.

Customizing the system message

The SDK gives you fine-grained control over the system message. Use SystemMessageMode.CUSTOMIZE to replace specific sections while preserving the rest:

SystemMessageConfig systemMessage = new SystemMessageConfig()
        .setMode(SystemMessageMode.CUSTOMIZE)
        .setSections(Map.of(SystemMessageSections.IDENTITY,
            new SectionOverride()
                .setAction(SectionOverrideAction.REPLACE)
                .setContent("""
                    You are part of a real estate recommendation system.
                    You will receive enquiries from customers, and you must
                    carry out the following workflow...
                    """)));

The text block ("""...""") makes multi-line prompts readable without string concatenation. The IDENTITY section override replaces only the model’s self-description while leaving safety guardrails intact. If you prefer a simpler approach, SystemMessageMode.APPEND adds your content after the default system message without replacing anything.

The agentic loop: sendAndWait(...)

One line kicks off the full agentic loop:

session = client.createSession(sessionConfig).get();
// ...
AssistantMessageEvent result = session.sendAndWait(escapedEnquiry).get();

Behind .get(), the model reasons, calls your tools (potentially multiple times), and returns its final response. On a virtual thread, .get() is cheap. No platform thread is consumed while waiting. The SDK dispatches tool calls to your registered handlers automatically and feeds results back to the model until it’s done.

Real-time event handling with session.on(...)

Subscribe to session events to build responsive UIs:

sessionSubscription = session.on(event -> {
    captureSessionEvent(event);
    uiUpdateSocket.pushDetailUpdate(id);
});

Every tool call, every result, every assistant message fires an event. The sample app captures these events and pushes them to the browser via Jakarta WebSocket, so the pipeline dashboard updates in real time. You can use pattern matching to handle specific event types:

if (event instanceof AssistantMessageEvent msg) {
    finalReport = msg.getData().content();
} else if (event instanceof ToolExecutionStartEvent start) {
    // Tool is being invoked...
}

Headless client and permission handling

The client is configured for server-side operation:

copilotClient = new CopilotClient(
        new CopilotClientOptions()
                .setMode(CopilotClientMode.EMPTY)
                .setCopilotHome(copilotHome)
                .setExecutor(contextualVirtualThreadExecutor));

CopilotClientMode.EMPTY means no IDE integration — the client talks directly to the Copilot CLI. The custom Executor (discussed below) ensures tool callbacks run with container context.

For permission handling, the sample uses:

sessionConfig.setOnPermissionRequest(PermissionHandler.APPROVE_ALL);

APPROVE_ALL is appropriate for demos and development. In production, implement a real permission policy that validates which tools the model is allowed to invoke.

Jakarta EE integration patterns

The SDK is not a framework island. It composes naturally with Jakarta EE — and of course also with proprietary frameworks such as Spring.

The Executor parameter is the key integration point. Jakarta Concurrency (§5.2 in the 3.1 spec) requires that application-created threads be obtained from a ManagedThreadFactory so the container can:

  1. Track the thread for lifecycle shutdown (@PreDestroy / server stop)
  2. Apply concurrency constraints and policies
  3. Propagate context automatically (without needing manual contextualRunnable)

Open Liberty 26.x supports virtual-thread ManagedThreadFactory via the virtual attribute in server.xml.

<managedThreadFactory jndiName="concurrent/virtualThreadFactory" virtual="true" />

Then, in AppState.java we inject the factory:

@Resource(lookup = "concurrent/virtualThreadFactory")
private ManagedThreadFactory virtualThreadFactory;

And use it to create the Executor we pass to the Copilot SDK.

// The ManagedThreadFactory (virtual=true) creates container-managed virtual
// threads that automatically propagate CDI, JNDI, and transaction context.
Executor managedVirtualExecutor = runnable ->
    virtualThreadFactory.newThread(runnable).start()

String copilotHome = Path.of(System.getProperty("user.home"), ".copilot").toString();
CopilotClientOptions copilotClientOptions = new CopilotClientOptions()
        .setMode(CopilotClientMode.EMPTY)
        .setCopilotHome(copilotHome)
        .setExecutor(managedVirtualExecutor);
copilotClient = new CopilotClient(copilotClientOptions);

This creates virtual threads that carry the container’s context. When the SDK dispatches a tool call to searchProperties(), that method can @Inject a JPA repository and query the database, because the container context is present on the callback thread.

Other integration patterns in the sample:

  • CDI @ApplicationScoped for the singleton CopilotClient (one client per application lifecycle).
  • Jakarta Faces f:websocket push for real-time browser updates via PushContext.
  • Jakarta Data @Repository for type-safe database queries without raw JPA boilerplate.

Fine-grained tool access control with ToolSet. The SessionConfig lets you specify exactly which tools each session can access:

sessionConfig.setAvailableTools(new ToolSet()
        .addCustom("*")           // all registered custom tools
        .addBuiltIn("web_fetch")); // only the web_fetch built-in

This is an important production concern. Rather than exposing every built-in tool (file system access, shell execution, etc.), you explicitly opt in to only what the agent needs. In the sample app, we allow all custom tools plus web_fetch so the agent can look up real-time property information during the Search phase.

Summary

Here’s what we covered:

  • Java-native API: CompletableFuture, annotations, lambdas, and virtual threads make the SDK feel like idiomatic Java, not a ported-from-another-language afterthought.
  • Three tool-definition styles: annotations for enterprise patterns, lambdas for inline convenience, JSON Schema for full control.
  • System message customization: section-level overrides give you precise control over agent behaviour.
  • The agentic loop in one line: sendAndWait(...) handles the full tool-calling loop automatically.
  • Real-time event streaming: session.on(...) enables responsive UIs and observability.
  • Headless server-side operation: no IDE required; runs anywhere the Copilot CLI is available.
  • Natural composition with Jakarta EE: CDI, JPA, WebSocket, and virtual threads all work together through the Executor integration point.

What to try next

  • Explore the BYOK support. The GitHub Copilot SDK can be used directly against model providers, for example OpenAI, Azure, Anthropic, or OpenAI-compatible endpoints, by passing a provider/ProviderConfig with your own baseUrl + apiKey (or bearer token). No Copilot subscription required.
  • Clone the sample app and run it locally. Submit multiple enquiries simultaneously to see virtual threads in action.
  • Swap the model. Try session.setModel(...) to experiment with different Copilot models.
  • Add your own tool. Define a new @CopilotTool method (a mortgage calculator, a school-district lookup) and watch the agent discover and use it.
  • Deploy to Azure. Open Liberty runs great on Azure App Service, AKS, or Azure Container Apps. See the Jakarta EE on Azure guidance at https://aka.ms/java/ee.

The Copilot SDK for Java puts the full power of GitHub Copilot behind your Java code with no IDE required and no framework lock-in.

Clone the sample app and try it yourself >

The post Using the GitHub Copilot SDK for Java appeared first on The GitHub Blog.
Migrating your Java applications to AWS Graviton using AWS Transform custom

Post Syndicated from Hahnara Hyun original https://aws.amazon.com/blogs/compute/migrating-your-java-applications-to-aws-graviton-using-aws-transform-custom/

For Java applications, modern JVMs like Amazon Corretto and OpenJDK are highly optimized for Arm64 and modern applications that are pure Java often require zero changes to run on Graviton. In many cases, applications aren’t fully modernized or purely Java and have a range of dependencies. When you’re responsible for migrating workloads, it’s helpful to use a systematic approach that surfaces issues, proposes solutions, and does the transformation work for you at scale.

That’s why we built the Java x86 to Graviton Migration transformation for AWS Transform custom (ATX). This is an AI-powered agent that analyzes your Java codebase, creates a migration plan, and executes the transformation—complete with version-controlled commits at every step. With ATX you can efficiently assess hundreds of Java applications simultaneously and quickly learn which applications require no changes and which ones need modifications. This streamlines the process of estimating the scope of effort, while also having suggested code updates before you even start.

ATX is available as a Kiro power, a VS Code extension, and an Agent Skill if you’d like to use it directly within other AI assistants to reduce context switching. While we will be using ATX to highlight how you can rapidly accelerate a Graviton migration, we have also published an open source Graviton universal skill based on the Agent Skills open standard so that you have the flexibility to use the skill natively within Kiro, Claude Code, Codex, or the platform of your choice.

AWS Graviton processors, based on the Arm64 architecture, can provide up to 40% better price performance over comparable x86-based instances for a wide variety of workloads. Now customers can use AI tools to quickly migrate workloads to Graviton.

The Java x86 to Graviton migration transformation

At a high level, we recommend customers finish any major version Java updates prior to migrating to Graviton and there’s a separate Java Version Upgrade transformation available for this use case. The Java x86 to Graviton Migration transformation requires a minimum of Java 8 and won’t incorporate Java version updates into the code changes.

The Java x86 to Graviton Migration completes multiple steps with work divided across multiple AI agents within the AWS Transform service, covering things like:

  • Native library analysis – Identifies Java Native Interface (JNI) dependencies and finds Arm64-compatible alternatives
  • Dependency updates – Updates libraries to versions with Arm64 support
  • Build configuration – Modifies Maven/Gradle configs for multi-architecture builds
  • Architecture-specific code – Refactors hard-coded x86 assumptions
  • Unit Test – Verifies compatibility at runtime given unit tests are in the project
  • Documentation – Creates migration notes and runbooks for your team

The agent automatically detects your Java version, manages runtime switching as needed during analysis, and handles much of the environment complexity for you such as multi-module project detection or Maven or Gradle auto-detection. Transformation completion times vary, but for many applications you can expect it to take roughly an hour (ATX works well with repos under 300K lines of code).

In this post, we:

  • Walk through the requirements for running the Java x86 to Graviton Migration transformation.
  • Help you familiarize yourself with ATX using a single Java application with Interactive Mode
  • Outline how to assess Graviton compatibility across the Java applications that you want to migrate to Graviton in a single batch and summarize the results with Campaign Mode.

By the end, you should have a good idea of how Java x86 to Graviton Migration transformation functions and have a summary of the expected code changes and dependency updates needed for each of your Java applications, along with version-controlled code updates.

Graviton transformation requirement

The Java x86 to Graviton migration transformation should run on an Arm64 machine.

The agent doesn’t just read your code, it builds, loads native libraries, and validates your application’s runtime behavior on Arm64. If you run the transformation on an x86 machine, the agent can identify compatibility issues but can’t execute build validation or run tests.

If you try to run on x86, you will see the following error message:

⚠  This transformation requires Arm64 architecture.    
Detected: x86_64        
Please run ATX on an Arm64 environment. See documentation for options.

To get started you need a Graviton instance or Apple Mac laptop running Arm64 with the ATX CLI, build tools, and Java JDKs that your project requires. The project source code should also be loaded locally onto the machine running the ATX CLI. Because Apple silicon is Arm64-based, it’s possible to build, load, and verify Arm64 based dependencies for a quick proof-of-concept. However, we recommend running the transformation in an environment that reflects what you plan to deploy in production to surface any potential OS level incompatibilities.

Requirements

Requirement Details
AWS Transform custom permissions AWS Identity and Access Management (IAM) policies for the Transform service (see Authentication docs)
Arm64 execution environment Amazon Elastic Compute Cloud (Amazon EC2) Graviton instance or Apple Silicon Mac. Running on x86 limits validation to static analysis only. Phase 3 (build/test) requires Arm64.
Node.js 20+ Required by the AWS Transform CLI. Use the official installer at nodejs.org/en/download. Package managers (dnf, yum) can install an older version.
Git AWS Transform custom uses local Git for version control during the transformation.
AWS Transform CLI Installed using the setup script (see Client Setup for the curl command).
Java build tooling A JDK (Arm64 build, e.g. Amazon Corretto or OpenJDK), Maven and/or Gradle as required by the target project. These are not optional for Java transformations. The agent needs them for dependency analysis, native library scanning, and build validation.

Running the Graviton transformation with Interactive Mode

With your code on an Arm64 environment and all the prerequisites for the transformation, we can begin the transformation.

Step 1: Navigate to Your Project and create or clone a git repo

cd /home/developer/workspace # Docker 
# or 
cd ~/workspace # AMI
git init

We recommend not pointing to the main branch of the repository of your application. You can work in a local git environment or create a separate branch. ATX needs the ability to commit changes as it iteratively transforms your code. The final decision on which commits are pushed is up to the developer.

Step 2: Launch ATX Interactive Mode

Enter the following command to launch ATX interactive mode.

atx

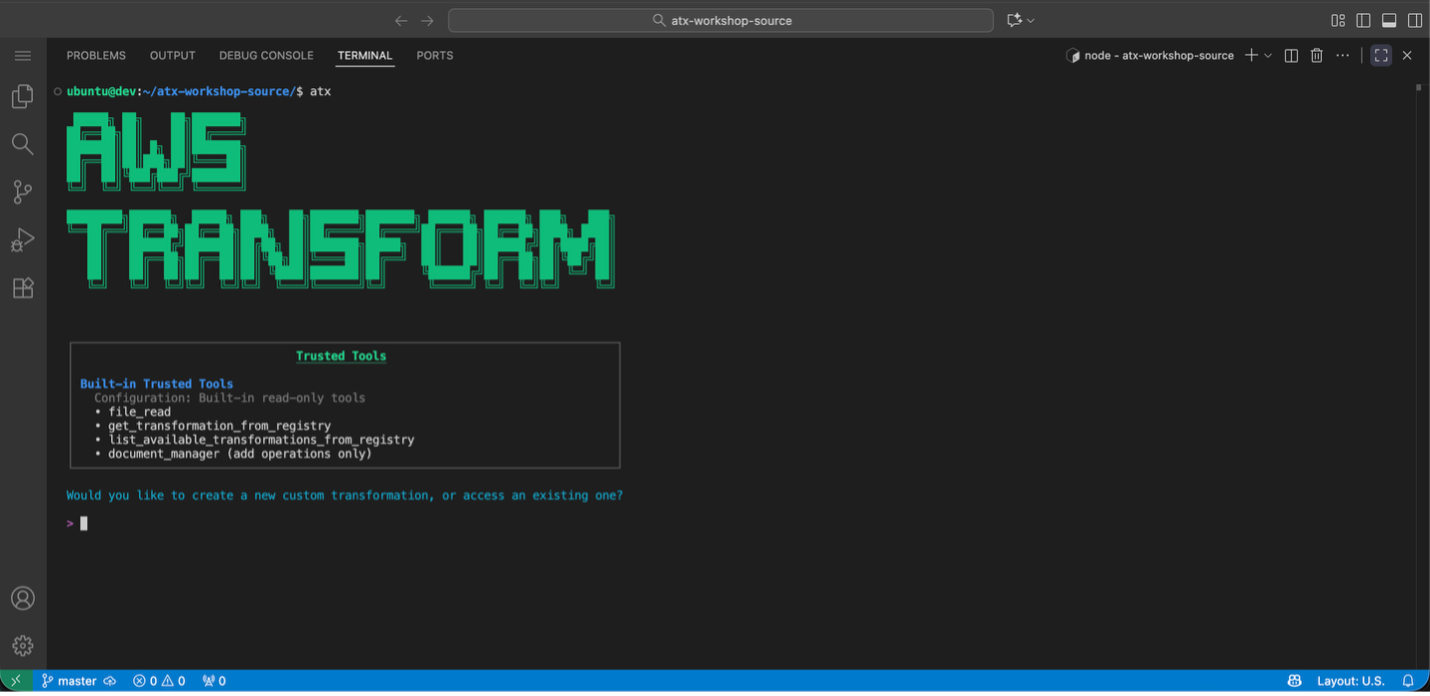
ATX starts in interactive mode:


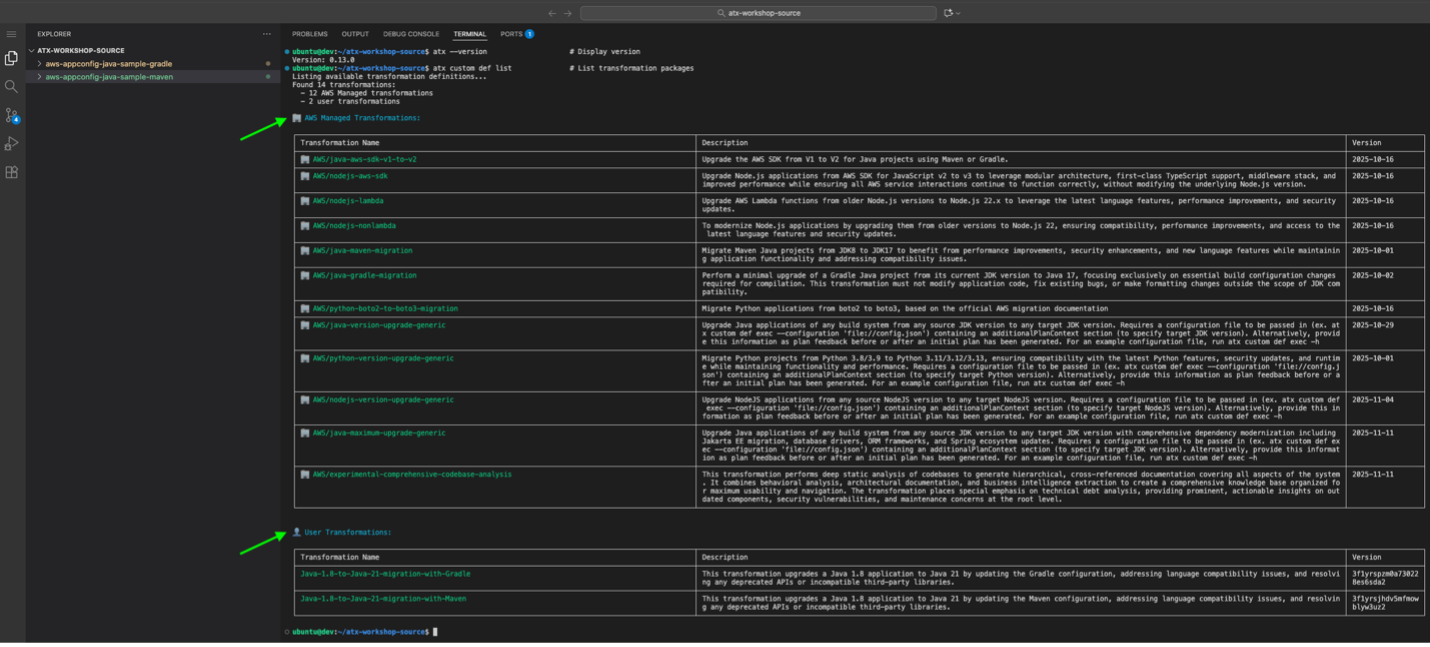
To view available transformations, in a separate terminal enter:

atx custom def list > custom_list.txt

The AWS Managed transformations will be listed first, followed by User-created transformations that you’ve developed.

Step 3: Select the Graviton transformation

Enter the following into atx cli:

>AWS/early-access-java-x86-to-graviton

ATX will prompt you for next steps and your project details:

> Would you like to:+ c to abort or provide feedback)
1. View the entire transformation definition
2. View specific sections of the transformation definition
3. Apply this transformation to your code
4. Modify this transformation
> 3
> What is the file system path to the code repository where you want to apply this transformation?
> .

Note that because this is an AWS Managed Transformation, you can’t view the complete transformation definition or modify it. However, you can provide additional context customized to your use case. Keep in mind that the Transformation won’t make permanent changes to your code through the transformation process.

Step 4: Provide additional context

ATX might ask clarifying questions to tailor the transformation:

Step 5: Review the analysis

ATX analyzes your codebase:

Analyzing your codebase...[████████████████████████████████████████] 100%
✓ Parsed 847 Java files
✓ Analyzed 234 dependencies  
✓ Identified 12 native library usages
✓ Scanned build configuration
✓ Evaluated test coverage
Analysis complete. Preparing migration plan...

Step 6: Review the migration plan

ATX presents a detailed plan before making changes:

═══════════════════════════════════════════════════════════════
                    MIGRATION PLAN
═══════════════════════════════════════════════════════════════

I've analyzed your project and here's what I'll do:

PHASE 1: Dependency Updates (12 changes)
────────────────────────────────────────
 • Update netty-transport-native-epoll 4.1.85 → 4.1.100
   Reason: Arm64 support added in 4.1.94
   
 • Update snappy-java 1.1.8.4 → 1.1.10.5  
   Reason: Current version lacks Arm64 native binaries
   
 • Update lz4-java 1.7.1 → 1.8.0
   Reason: Arm64 optimization improvements
   
 • ... (9 more dependency updates)

PHASE 2: Build Configuration (3 changes)
────────────────────────────────────────
 • Add Arm64 classifier to native dependency declarations
 • Configure multi-architecture Docker build
 • Add Graviton-optimized JVM flags to startup scripts

PHASE 3: Code Modifications (2 changes)
────────────────────────────────────────
 • Refactor ProcessorArchitecture.java
   Current: Hard-coded x86_64 assumption
   Change: Add Arm64 detection logic
   
 • Update NativeLibraryLoader.java
   Current: Loads x86-specific .so files
   Change: Architecture-aware library loading

PHASE 4: Testing & Validation
────────────────────────────────────────
 • Run build and tests on Arm64
 • Generate migration report and documentation

═══════════════════════════════════════════════════════════════

? How would you like to proceed?
  ❯ Execute the full plan
    Execute phase by phase (review each)
    Modify the plan
    Ask questions about the plan
    Export plan and exit

Step 7: Ask questions, request changes

This is your chance to understand and adjust:

? Ask questions about the plan:

You: Why are you updating netty to 4.1.100? 

ATX: Good concern. Netty 4.1.94 was the first version with Arm64 
     native transport support, which is required for optimal 
     performance on Graviton. 
     
     However, I can adjust this:
     
     Option 1: Use 4.1.94 (minimum Arm64 support)
     Option 2: Use 4.1.97 (includes Arm64 bug fixes)
     Option 3: Keep 4.1.100 (latest stable with Arm64)
     
     Which would you prefer?

You: Let's go with 4.1.100.

Step 8: Execute the Transformation

When you’re ready:

? How would you like to proceed?
  ❯ Execute the full plan

Starting transformation...

Phase 1: Dependency Updates
───────────────────────────
[1/12] Updating netty-transport-native-epoll...
       ✓ Modified pom.xml
       ✓ Committed: "chore(deps): update netty to 4.1.97 for Arm64 support"

[2/12] Updating snappy-java...
       ✓ Modified pom.xml  
       ✓ Committed: "chore(deps): update snappy-java to 1.1.10.5 for Arm64"

... (progress continues)

Phase 2: Build Configuration
───────────────────────────
[1/3] Adding Arm64 classifiers...
      ✓ Modified pom.xml
      ✓ Committed: "build: add Arm64 native classifiers"

... (progress continues)

Phase 3: Code Modifications
───────────────────────────
[1/2] Refactoring ProcessorArchitecture.java...
      ✓ Modified src/main/java/com/example/util/ProcessorArchitecture.java
      ✓ Committed: "feat: add Arm64 architecture detection"

... (progress continues)

Phase 4: Validation
───────────────────
Running build... ✓
Running tests... ✓ (847 passed, 0 failed)

═══════════════════════════════════════════════════════════════
                 TRANSFORMATION COMPLETE
═══════════════════════════════════════════════════════════════

Summary:
 • 17 files modified
 • 3 files created  
 • 14 commits made
 • All tests passing

Generated Artifacts:
 • GRAVITON_MIGRATION_REPORT.html  - Full migration report
 • MIGRATION_RUNBOOK.md            - Deployment guide for your team
 • commit-log.txt                  - All commits with descriptions

Your code is now Graviton-ready!

After the transformation is complete, you can now performance test and load test on Graviton instances to configure your scaling policies or target thresholds to maximize price/performance on Graviton. For more guidance on performance testing, see the AWS Graviton Technical Guide.

What you get after transformation

Version-controlled history

Every logical change is a separate commit:

$ git log --oneline -10

a3f2b1c (HEAD) docs: add Graviton migration runbook
b82d4e5 test: add Arm64 architecture verification tests
c9a1f3d feat: add Arm64 architecture detection
d4e7c2a build: configure multi-arch Docker build
e5f8d1b build: add Arm64 native classifiers
f6a9e2c chore(deps): update lz4-java to 1.8.0
g7b0f3d chore(deps): update snappy-java to 1.1.10.5
h8c1a4e chore(deps): update netty to 4.1.97 for Arm64 support
...

Each commit is atomic and revertible. If something doesn’t work, you can git revert specific changes.

Migration report

A comprehensive markdown report covering:

  • What was changed and why
  • Dependencies that were updated
  • Code modifications with before and after diffs
  • Performance optimization recommendations

Migration runbook

A deployment guide for your team:

  • Pre-deployment checklist
  • JVM flags designed for Graviton
  • Monitoring and rollback procedures

Additional resources on migrating to Graviton on an infrastructure level can be found in the Transition Guide.

Assessing Graviton compatibility for multiple Java applications with Campaign Mode

When you’re ready to start migrating multiple applications, you might want to opt for an automated process that removes the manual effort of going back and forth with the transformation agent after each transformation step with campaign mode. The following command allows ATX CLI to go through a full transformation that you can check back in with after it’s completed. This limits the additional customization and context that you might want to provide the agent.

As mentioned in the first step of running a Graviton Transformation, the environment that the code is transformed in and decision of which commits are pulled into the main repo is up to the developer. Running in campaign mode across several applications doesn’t require accepting and pushing code changes. Therefore, this automated method is most useful when you want to gauge a high-level overview of effort required to migrate across several or even hundreds of applications.

atx custom def exec \
--code-repository-path /path/to/myapp \
--non-interactive \
--trust-all-tools \
--campaign  \
--repo-name myapp \
--add-repo

This command can be added into scripts, allowing further automations to be built into continuous integration and delivery (CI/CD) pipelines or scaling transformation jobs across several repos without manually entering prompts as previously shown through interactive mode.

The status of transformations running with campaign mode will be displayed in the AWS Transform Web UI. Setting up the Web UI is a prerequisite to running a transformation in campaign mode.

In addition to this view, if you run the transformation across multiple applications, you can generate a consolidated dashboard with an agent of your choice. Gather the transformation results into a centralized directory, then use the following prompt for example:

Analyze all Java application Graviton transformation summaries in <directory>/<path>/ and create a comprehensive dashboard that includes: 
 
1. Executive summary with key metrics (total apps, compatibility rate, code changes required) 
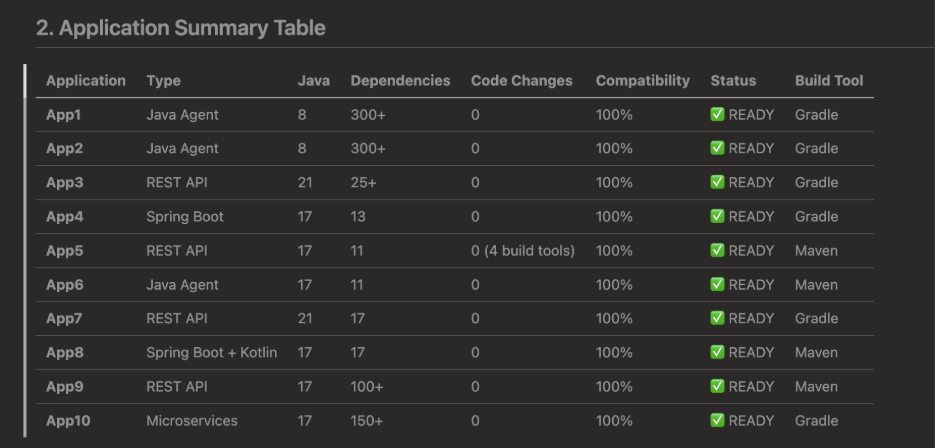
2. Application summary table with columns: Application name, Type, Java version, Dependencies count, Code changes, Compatibility %, Status 
3. Code changes analysis - which apps needed changes and why 
4. Dependency transformation analysis - common dependencies and their ARM64 status, any upgrades required 
5. Native library analysis - which apps use native libs and their compatibility 
6. Performance expectations - JWT/crypto improvements, general performance gains, cost-performance ratios 
7. JVM optimization patterns - common flags used across applications 
8. Build system patterns - Maven/Gradle usage, Docker multi-arch support 
9. Test results summary - pass/fail rates, pre-existing vs ARM64 issues 
10. Common libraries requiring changes (or note if none) 
11. Deployment readiness assessment 
12. Risk assessment with mitigation strategies 
13. Migration recommendations with phased approach 
14. Documentation summary - total docs created and their coverage 
 
Read graviton-validation/00-summary.md from each application subdirectory. Consolidate findings into a single comprehensive markdown dashboard with tables, metrics, and actionable insights. 
 
Focus on: compatibility rates, code change requirements, dependency issues, performance expectations, and migration readiness. 

Keep in mind that agents might output outcomes of the migration that aren’t sourced from the transformation summaries. As a result, we recommend that you use the summary as a high-level estimate of the technical effort required for migrating to Graviton.

Conclusion

The AWS Transform custom Java x86 to Graviton Migration transformation alleviates the guesswork in Graviton migrations by using AI for dependency analysis, compatibility assessment, code refactoring, and runtime validation. Development teams can evaluate hundreds of Java applications simultaneously, with each transformation providing atomic version-controlled commits for straightforward rollback and clear change tracking. The tool offers two modes: 1) interactive mode for hands-on, application-by-application migration with developer review at each step, or 2) campaign mode for automated assessment across multiple applications. ATX converts unknown Graviton migration effort into defined requirements through automated compilation and runtime testing. This provides a more efficient way to evaluate workload compatibility and migrate to Graviton.

The Java x86 to Graviton Migration transformation is one of a range of pre-built AWS Managed Transformations but you can also create custom transformations unique to your own use case that can be scaled to drive migrations across your organization. Learn more on the AWS Transform custom website or documentation.

Resources

Scaling ArchUnit with Nebula ArchRules

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/scaling-archunit-with-nebula-archrules-b4642c464c5a

By John Burns and Emily Yuan

Introduction

At Netflix, we operate using a polyrepo strategy with tens of thousands of Java repositories. This means that we need to have ways of sharing common build logic across these repositories. On the JVM Ecosystem team within Java Platform, we build tooling such as the Nebula suite of Gradle plugins to provide standard ways to build projects, keep dependencies up-to-date, and publish artifacts reliably across the Java ecosystem. Our mission also entails providing build-time feedback to the developer when they deviate from the paved road, or when their code base contains technical debt.

Case Study

After a Netflix incident relating to a library releasing a backwards-incompatible change, our team was asked to provide some tooling and practices to improve the Java library lifecycle management. This was not a simple case of a library making a reckless breaking change. The code removed had been deprecated for years. Library authors often struggle to know when it is safe to remove deprecated code, or refactor code that is not meant to be used by downstream applications. Fleet-wide migrations, such as upgrading major Spring Boot versions, also involve deprecated code removal. To help with this, we established a suite of API lifecycle annotations:

  • @Deprecated from the Java standard library
  • @Public A custom annotation to use on APIs meant to be used downstream
  • @Experimental A custom annotation for new APIs which may not yet be stable
  • All other APIs are assumed to be “internal”

Library authors can annotate their APIs with these annotations. However, how will they know which downstream projects are using their API incorrectly, based on these?

As we sought to improve the paved road for JVM-based libraries at Netflix, we needed a good way of identifying this kind of technical debt, not only for the benefit of the Java Platform-provided libraries, but any team delivering shared libraries to the organization. For this, we looked at ArchUnit.

ArchUnit is a popular OSS library (3.5k stars, 84 contributors) used to enforce “architectural” code rules as part of a JUnit suite. It is used internally by Gradle, Spring, and is provided as part of the Spring Modulith platform. The rules engine, which is built directly on top of ASM, can be used for a wide variety of use cases. It is powerful enough to be a general purpose static analysis tool with the following distinctive features:

1. Works cross-language (JVM), because it uses ASM/bytecode, not AST parsing.

2. Exposes a builder API pattern that makes it easy to write rules

3. Also has a lower level API ideal for writing more complex custom rules.

The limitation of ArchUnit is that it is designed to be used as part of a JUnit suite in a single repository. The Nebula ArchRules plugins give organizations the ability to share and apply rules across any number of repositories. Rules can be sourced from OSS libraries or private internal libraries. This makes the plugin generally useful for any JVM+Gradle engineering organization.

Why ArchUnit?

Before we go into how ArchRules works, it is good to understand why we would want to use ArchUnit in this way instead of other static analysis tools.

AST vs Bytecode

Some tools, such as PMD, process rules against an AST (abstract syntax tree). An AST is a structured representation of source code. This kind of tool will have rules that are syntax dependent. Rules that need to support multiple JVM languages, such as Kotlin or Scala, often need to be rewritten for each language. It also allows code which should be found to be hidden under syntactic sugar not anticipated by the rule author. ArchUnit uses ASM to analyze actual compiled bytecode, which means it doesn’t matter how that code was produced. What is analyzed is the actual code that will be run.

Rule Authorship

Tools like PMD and Spotbugs are not optimized for custom rule authorships. Most usage of these tools run built-in provided rules, or add in pre-made third party plugins. Take a look at what a custom rule for PMD might look like:

<![CDATA[
//AllocationExpression/ClassOrInterfaceType[
@Image='DateTime' and (
(count(..//Name[@Image='DateTimeZone.UTC'])<=0)
and
(count(..//Name[@Image='DateTimeZone.forID'])<=0)
) or (
(
(count(..//Name[@Image='DateTimeZone.UTC'])>0)
or
(count(..//Name[@Image='DateTimeZone.forID'])>0)
) and (../Arguments/ArgumentList and count(../Arguments/ArgumentList/Expression) = 1)
)
]
]]>

This rule ensures that DateTimes are not instantiated without an explicit zone. This is a raw string meant to be used within PMD’s xpath parser. There is no IDE guidance on crafting it. To test it, a whole separate PMD process needs to be wired up to interpret the rule and evaluate it against a source file. Let’s see how a similar rule would look with ArchUnit:

ArchRuleDefinition.priority(Priority.MEDIUM)
.noClasses()
.should()
.callConstructorWhere(
// constructor does not have a zone arguement
target(doesNot(have(rawParameterTypes(DateTimeZone.class))))
// constructor is for DateTime
.and(targetOwner(assignableTo(DateTime.class)))
)

This is type-safe Java code with a fluent API. It is also simple to unit test, as ArchUnit has a method to pass a rule object and class references to evaluate the rule against those classes.

Class Relations

Because ArchUnit processes the entire classpath with ASM, it retains a graph of the class data, allowing rules to easily traverse class relationships and call sites. This allows rules to have much more context about the code it is evaluating.

Rules Libraries

The first step was to build the ability to write ArchUnit rules which can be shared and published. In order to do this, we have the ArchRules Library Plugin. This plugin adds an additional source set to your Gradle project called archRules. In this source set, you can create a class which implements the ArchRulesService interface. This interface has a single abstract method which returns a Map<String, ArchRule>. The keys of this map are the names of your rules, and the ArchRule is the rule you would like to define using the standard ArchUnit API. Here is an example:

public class GuavaRules implements ArchRulesService {
static final ArchRule OPTIONAL = ArchRuleDefinition.priority(Priority.MEDIUM)
.noClasses()
.should()
.dependOnClassesThat()
.haveFullyQualifiedName("com.google.common.base.Optional")
.because("Java Optional is preferred over Guava Optional");

@Override
public Map<String, ArchRule> getRules() {
Map<String, ArchRule> rules = new HashMap<>();
rules.put("guava optional", OPTIONAL);
return rules;
}
}

This code and its dependencies will not be bundled with your main code. It is bundled into a separate Jar with the arch-rules classifier. When publishing, your library will publish this jar as a separate variant with the usage attribute set to arch-rules. This means that in order for downstream projects to use these rules, they must use Gradle Module Metadata for dependency resolution. There are 2 flavors of rules Libraries: Standalone rules libraries, bundled rule libraries.

Standalone Rule Libraries

A Standalone Rule library contains no main code: only archRules. These are useful for defining rules for code you don’t own, such as Core Java APIs or OSS libraries. They are also useful for generic rules that can apply to any code, such as “don’t use code marked as @Deprecated”. We maintain a collection of OSS Standalone rule libraries which anyone is free to use, and serve as examples of the types of rules you may want to write yourself. However, the real power of ArchRules is in “bundled rule libraries”.

Bundled Rule Libraries

A bundled rule library is a library with both main and archRules sources. The main source set will contain useful library code, whatever it may be. The archRules will contain rules specific to the usage of that library. For example, rules scoped to that library’s package, or referencing that library’s specific API. Whenever possible, we recommend writing rules in this bundled way. That is because the ArchRules Runner Plugin will be able to automatically detect these rules and run them in only the source sets that use this library as a dependency. An example of this can be seen in our Nebula Test library.

In any case, the library plugin will automatically generate a service loader registration entry for your ArchRulesService so that the runner can discover your rules.

Running Rules

The ArchRules Runner Plugin allows rules to be evaluated against your code. Standalone rule libraries can be evaluated against all source sets by adding them to the archRules configuration in your build. For example:

dependencies {
archRules("your:rules:1.0.0")
}

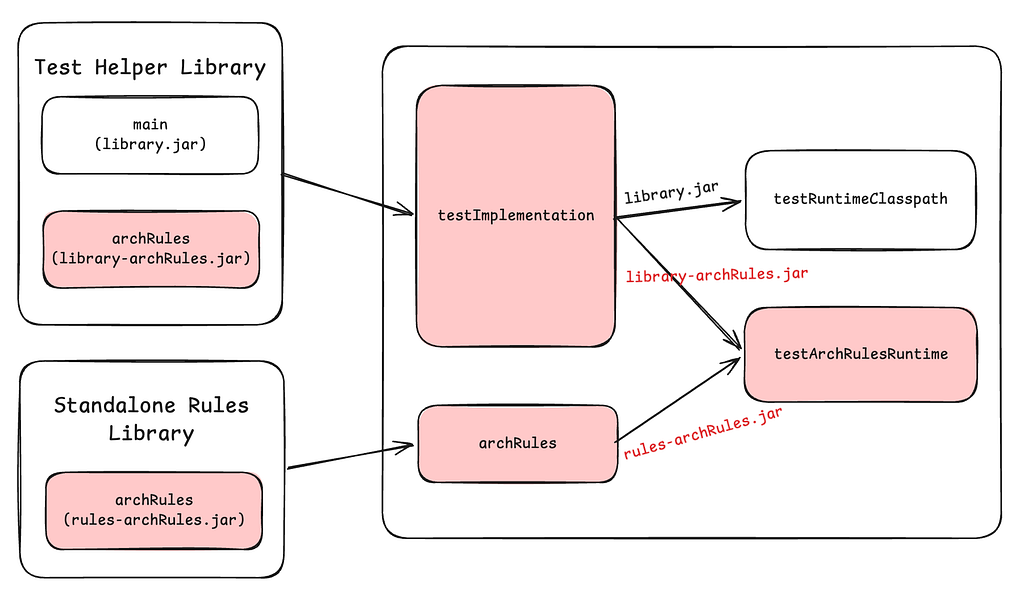
As mentioned before, bundled rules will be evaluated automatically. To do this, the runner plugin creates a separate configuration for each of your source sets. In each of these configurations, the archRules classpath is combined with the runtimeClasspath with the arch-rules variant selected. This configuration is the classpath used when the ServiceLoader discovers implementations of ArchRulesService. In the following example, we have a Project which uses a test helper library as a testImplementation dependency, and also adds a standalone rules library to the archRules configuration. The test runtime classpath will only contain the implementation jar for the helper library, but the arch rules runtime will contain the archrules jar for the bundled rules and standalone rules. This all happens automatically.

Gradle configurations used by ArchRules

Once the rules classpath is determined, the runner plugin will create a Gradle work action to evaluate rules against that specific source set. This action runs with classpath isolation using the *archRuleRuntime configuration. Within this action, a ServiceLoader is used to discover rule definitions. The action ends by writing a binary serialization of rule violations to a file for reporting.

In a project running rules, you also have the ability to customize rule configurations using the archRules extension. For example, you can override a rule’s priority level:

archRules {
ruleClass("com.netflix.nebula.archrules.deprecation") {
priority("HIGH")
}
}

Other customizations include disabling running rules on certain source sets and configuring the failure threshold (i.e., high priority failures will cause the build to fail).

Reporting

The ArchRules runner plugin has two built-in reports: JSON and console. The json report will collect the output from all source sets within a project and create a single json file with all of the data. The console report also collects the output from all source sets within a project, but it prints to the console an easy to read report, for example:

Console Report output

Note that failure details feature a detailed plain English description, along with a pointer to the exact line of code in violation.

For custom reporting, you can either use the JSON file, or create your own task that reads the binary files. Take a look at the source code for the ArchRules runner plugin’s report tasks for an example of how to do this.

Case Study Solution

Going back to our original problem, using ArchRules, we were able to deliver a platform for library authors to track the usage of their APIs. They write ArchRules to detect usage of the annotations, scoped to their library’s package, such as:

ArchRuleDefinition.priority(Priority.MEDIUM)
.noClasses().that(resideOutsideOfPackage(packageName + ".."))
.should()
.dependOnClassesThat(resideInAPackage(packageName + "..").and(are(deprecated())))
.orShould().accessTargetWhere(targetOwner(resideInAPackage(packageName + ".."))
.and(target(is(deprecated())).or(targetOwner(is(deprecated())))))
.allowEmptyShould(true)
.because("Deprecated APIs are subject to removal");

NB: the deprecated() predicate comes from nebula-archrules.

Our internal Nebula standard Gradle wrapper and plugin suite automatically enable the ArchRules runner on every project, and provides a custom reporter which sends the report data to our Internal Developer Portal on every main-branch CI build. This way, library authors can easily see a report of all downstream consumers using their experimental, deprecated, or non-public APIs, giving them confidence to make “breaking” changes, knowing that it will not actually break downstream consumers. If their changes are currently blocked by downstream usage, they can easily see exactly which projects are reporting those usages.

OSS Rule Libraries

While the most powerful way to use ArchRules is for you to write your own rules, we have built some OSS rule libraries that anyone is free to use, or reference as examples.

Nullability

These rules enforce proper nullability annotation in Java, for example, that every public class is marked with JSpecify’s @NullMarked. It is smart enough to exclude Kotlin code, as Kotlin has built-in nullability.

Gradle Plugin Best Practices

Writing Gradle plugins can be hard, especially since there are many APIs and patterns that should not be used anymore. These rules help enforce current best practices when writing Gradle plugins.

Joda / Guava Rules

These rule libraries discourage the use of Joda Time and Guava classes (respectively) as these have been superseded by java.time and standard library enhancements.

Security Rules

These rules help mitigate CVEs by detecting usage of known vulnerable APIs. Ideally, we keep dependencies up to date to mitigate CVEs. But sometimes that is not immediately feasible, and in those cases, a compile time check to ensure the specific vulnerable API is not used is often good enough.

Conclusion

We are now running 358 (and counting) rules across over 5,000 repositories detecting over nearly 1 million issues. About 1,000 of these issues are for “High” priority rules. Being able to run these rules on this scale allows us to quickly gain insight into our large fleet of microservices, and identify the areas carrying the most critical technical debt. This makes it easier to focus and prioritize our efforts.

Going forward, we will be exploring how to tie auto-remediation solutions into the ArchRules findings. ArchUnit currently provides very specific and detailed information about failures in reports, which makes a very strong input signal to an auto remediation tool. We will explore deterministic solutions such as OpenRewrite and non-deterministic solutions such as LLMs. Pairing the easy rule authorship and deterministic results of ArchUnit with an auto-remediation tool that can correctly interpret the results to solve the issue at hand will be a very powerful combination.

We also will investigate how to get ArchRule failure information surfaced in the IDE as inspections.

If you have questions or feedback about Nebula ArchRules, reach out to us by posting in the #nebula channel on the Gradle Community Slack.


Scaling ArchUnit with Nebula ArchRules was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Optimizing Recommendation Systems with JDK’s Vector API

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/optimizing-recommendation-systems-with-jdks-vector-api-30d2830401ec

By Harshad Sane

Ranker is one of the largest and most complex services at Netflix. Among many things, it powers the personalized rows you see on the Netflix homepage, and runs at an enormous scale. When we looked at CPU profiles for this service, one feature kept standing out: video serendipity scoring — the logic that answers a simple question:

“How different is this new title from what you’ve been watching so far?”

This single feature was consuming about 7.5% of total CPU on each node running the service. What started as a simple idea — “just batch the video scoring feature” — turned into a deeper optimization journey. Along the way we introduced batching, re-architected memory layout and tried various libraries to handle the scoring kernels.

Read on to learn how we achieved the same serendipity scores, but at a meaningfully lower CPU per request, resulting in a reduced cluster footprint.

Problem: The Hotspot in Ranker

At a high level, serendipity scoring works like this: A candidate title and each item in a member’s viewing history are represented as embeddings in a vector space. For each candidate, we compute its similarity against the history embeddings, find the maximum similarity, and convert that into a “novelty” score. That score becomes an input feature to the downstream recommendation logic.

The original implementation was straightforward but expensive. For each candidate we fetch its embedding, loop over the history to compute cosine similarity one pair at a time and track the maximum similarity score. Although it is easy to reason about, at Ranker’s scale, this results in significant sequential work, repeated embedding lookups, scattered memory access, and poor cache locality. Profiling confirmed this.

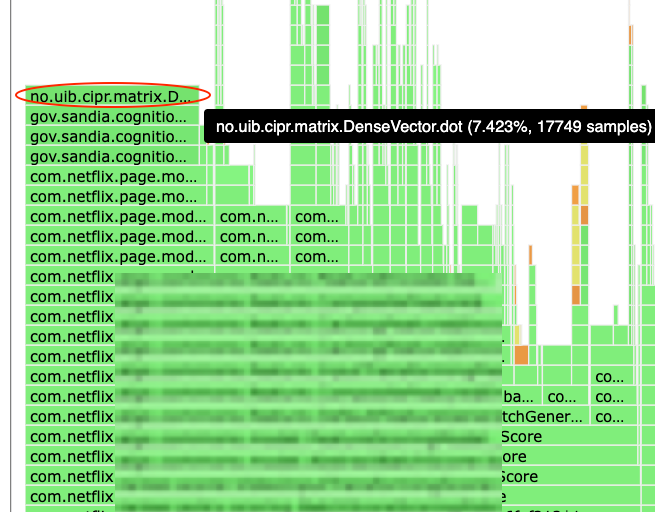
Flamegraph showing inefficient scoring

A flamegraph made it clear: One of the top hotspots in the service was Java dot products inside the serendipity encoder. Algorithmically, the hotspot was a nested loop structure of M candidates × N history items where each pair generates its own cosine similarity i.e. O(M×N) separate dot product operations.

Solution

The Original Implementation: Single video cosine loop

In simplified form the code looked like this:

for (Video candidate : candidates) {
Vector c = embedding(candidate); // D-dimensional
double maxSim = -1.0;

for (Video h : history) {
Vector v = embedding(h); // D-dimensional
double sim = cosine(c, v); // dot(c, v) / (||c|| * ||v||)
maxSim = Math.max(maxSim, sim);
}

double serendipity = 1.0 - maxSim;
emitFeature(candidate, serendipity);
}

The nested for loop with O(M×N) separate dot products brought upon its own overheads. One interesting detail we learned by instrumenting traffic shapes: most requests (about 98%) were single-video, but the remaining 2% were large batch requests. Because those batches were so large, the total volume of videos processed ended up being roughly 50:50 between single and batch jobs. This made batching worth pursuing even if it didn’t help the median request.

Step 1 : Batching, from Nested Loops to Matrix Multiply

The first idea was to stop thinking in terms of “many small dot products” and instead treat the work as a matrix operation. i.e. For batch candidates, implement a data layout to parallelize the math in a single operation i.e. matrix multiply. If D is the embedding dimension:

  1. Pack all candidate embeddings into a matrix A of shape M x D
  2. Pack all history embeddings into a matrix B of shape N x D
  3. Normalize all rows to unit length.
  4. Compute: cosine similarities as
    [ C = A x B^T ]; where C is an M x N matrix of cosine similarities.

In pseudo‑code:

// Build matrices
double[][] A = new double[M][D]; // candidates
double[][] B = new double[N][D]; // history

for (int i = 0; i < M; i++) {
A[i] = embedding(candidates[i]).toArray();
}
for (int j = 0; j < N; j++) {
B[j] = embedding(history[j]).toArray();
}

// Normalize rows to unit vectors
normalizeRows(A);
normalizeRows(B);

// Compute C = A * B^T
double[][] C = matmul(A, B);
C[i][j] = cosine(candidates[i], history[j])

// Derive serendipity
for (int i = 0; i < M; i++) {
double maxSim = max(C[i][0..N-1]);
double serendipity = 1.0 - maxSim;
emitFeature(candidates[i], serendipity);
}

This turns M×N separate dot products into a single matrix multiply, which is exactly what CPUs and optimized kernels are built for. We integrated this into the existing framework by supporting both, encode()for single videos and batchEncode() for batches, while maintaining backward compatibility. At this point it seemed like we were “done”, but we weren't.

Step 2: When Batching Isn’t Enough

Once we had a batched implementation, we ran canaries and saw something surprising: about a 5% performance regression. The algorithm wasn’t the issue — turning M×N separate dot products into a matrix multiplication is mathematically sound. The problem was the overhead we introduced in the first implementation.

  1. Our initial version built double[][] matrices for candidates, history, and results on every batch. Those large, short-lived allocations created GC pressure, and the double[][] layout itself is non-contiguous in memory, which meant extra pointer chasing and worse cache behavior.
  2. On top of that, the first-cut Java matrix multiply was a straightforward scalar implementation, so it couldn’t take advantage of SIMD. In other words, we paid the cost of batching without getting the compute efficiency we were aiming for.

The lesson was immediate: algorithmic improvements don’t matter if the implementation details—memory layout, allocation strategy, and the compute kernel—work against you. That set up the next step for making the data layout cache-friendly and eliminating per-batch allocations before revisiting the matrix multiply kernel.

Step 3: Flat Buffers & ThreadLocal Reuse

We reworked the data layout to be cache-friendly and allocation-light. Instead of double[m][n], we moved to flat double[] buffers in row-major order. That gave us contiguous memory and predictable access patterns. Then we introduced a ThreadLocal<BufferHolder> that owns reusable buffers for candidates, history, and any other scratch space. Buffers grow as needed but never shrink, which avoids per-request allocation while keeping each thread isolated (no contention). A simplified sketch:

class BufferHolder {  
double[] candidatesFlat = new double[0];
double[] historyFlat = new double[0];

double[] getCandidatesFlat(int required) {
if (candidatesFlat.length < required) {
candidatesFlat = new double[required];
}
return candidatesFlat;
}

double[] getHistoryFlat(int required) {
if (historyFlat.length < required) {
historyFlat = new double[required];
}
return historyFlat;
}
}

private static final ThreadLocal<BufferHolder> threadBuffers =
ThreadLocal.withInitial(BufferHolder::new);

This change alone made the batched path far more predictable: fewer allocations, less GC pressure, and better cache locality.

Now the remaining question was the one we originally thought we were answering: what’s the best way to do the matrix multiply?

Step 4: BLAS: Great in Tests, Not in Production

The obvious next step was BLAS (Basic Linear Algebra Subprograms). In isolation, microbenchmarks looked promising. But once integrated into the real batch scoring path, the gains didn’t materialize. A few things were working against us:

  • The default netlib-java path was using F2J (Fortran-to-Java) BLAS rather than a truly native implementation.
  • Even with native BLAS, we paid overhead for setup and JNI transitions.
  • Java’s row-major layout doesn’t match the column-major expectations of many BLAS routines, which can introduce conversion and temporary buffers.
  • Those extra allocations and copies mattered in the full pipeline, especially alongside TensorFlow embedding work.

BLAS was still a useful experiment — it clarified where time was being spent, but it wasn’t the drop-in win we wanted. What we needed was something that stayed pure Java, fit our flat-buffer architecture, and could still exploit SIMD.

Step 5: JDK Vector API to the rescue

A Short Note on the JDK Vector API: The JDK Vector API is an incubating feature that provides a portable way to express data-parallel operations in Java — think “SIMD without intrinsics”. You write in terms of vectors and lanes, and the JIT maps those operations to the best SIMD instructions available on the host CPU (SSE/AVX2/AVX-512), with a scalar fallback when needed. More crucially for us, it’s pure Java: no native dependencies, no JNI transitions, and a development model that looks like normal Java code rather than platform-specific assembly or intrinsics.

This was a particularly good match for our workload because we had already moved embeddings into flat, contiguous double[] buffers, and the hot loop was dominated by large numbers of dot products. The final step was to replace BLAS with a pure-Java SIMD implementation using the JDK Vector API. By this point we already had the right shape for high performance — batching, flat buffers, and ThreadLocal reuse. So the remaining work was to swap out the compute kernel without introducing JNI overhead or platform-specific code. We did that behind a small factory. At class load time, MatMulFactory selects the best available implementation:

  • If jdk.incubator.vector is available, use a Vector API implementation.
  • Otherwise, fall back to a scalar implementation with a highly optimized loop-unrolled dot product (implemented by my colleague Patrick Strawderman, inspired by patterns used in Lucene)

In the Vector API implementation, the inner loop computes a dot product by accumulating a * b into a vector accumulator using fma() (fused multiply-add). DoubleVector.SPECIES_PREFERRED lets the runtime pick an appropriate lane width for the machine. Here’s a simplified sketch of the inner loop:

// Vector API path (simplified)  
for (int i = 0; i < M; i++) {
for (int j = 0; j < N; j++) {

DoubleVector acc = DoubleVector.zero(SPECIES);
int k = 0;
// SPECIES.length() (e.g. often 4 doubles on AVX2 and 8 doubles on AVX-512).
for (; k + SPECIES.length() <= D; k += SPECIES.length()) {
DoubleVector a = DoubleVector.fromArray(SPECIES, candidatesFlat, i*D + k);
DoubleVector b = DoubleVector.fromArray(SPECIES, historyFlat, j*D + k);
acc = a.fma(b, acc); // fused multiply-add
}
double dot = acc.reduceLanes(VectorOperators.ADD);
// handle tail k..D-1
similaritiesFlat[i*N + j] = dot;
}
}

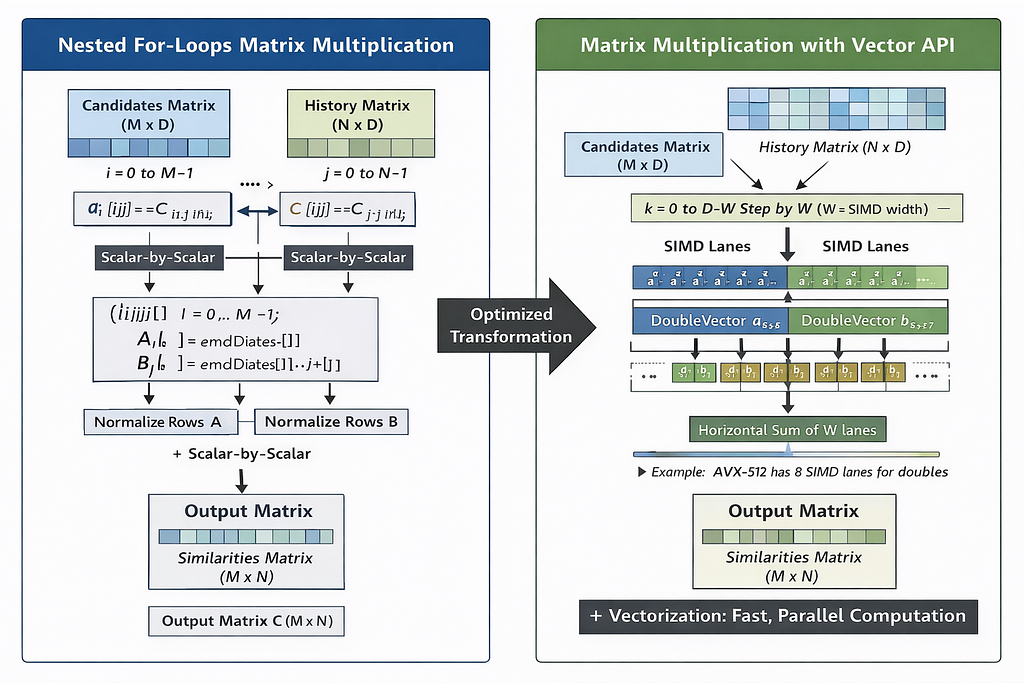
Figure below shows how the Vector API utilizes SIMD hardware to process multiple doubles per instruction (e.g., 4 lanes on AVX2 and 8 lanes on AVX‑512). What used to be many scalar multiply-adds becomes a smaller number of vector fma() operations plus a reduction—same algorithm, much better use of the CPU’s vector units.

Vectorization with SIMD

Fallbacks & Safety: When the Vector API Isn’t Available

Because the Vector API is still incubating, it requires a runtime flag: –add-modules=jdk.incubator.vector We didn’t want correctness or availability to depend on that flag. So we designed the fallback behavior explicitly: At startup, we detect Vector API support and use the SIMD batched matmul when available; otherwise we fall back to an optimized scalar path, with single-video requests continuing to use the per-item implementation.

That gives us a clean operational story: services can opt in to the Vector API for maximum performance, but the system remains safe and predictable without it.

Results in Production:

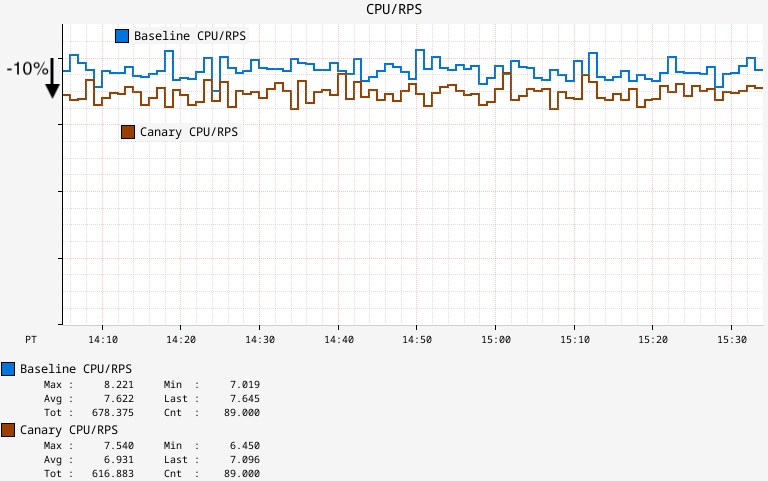
With the full design in place with batching, flat buffers, ThreadLocal reuse, and the Vector API, we ran canaries that run production traffic. We observed a ~7% drop in CPU utilization and ~12% drop in average latency. To normalize across any small throughput differences, we also tracked CPU/RPS (CPU consumed per request-per-second). That metric improved by roughly 10%, meaning we could handle the same traffic with about 10% less CPU, and we saw similar numbers hold after full production rollout.

CPU/RPS on Ranker

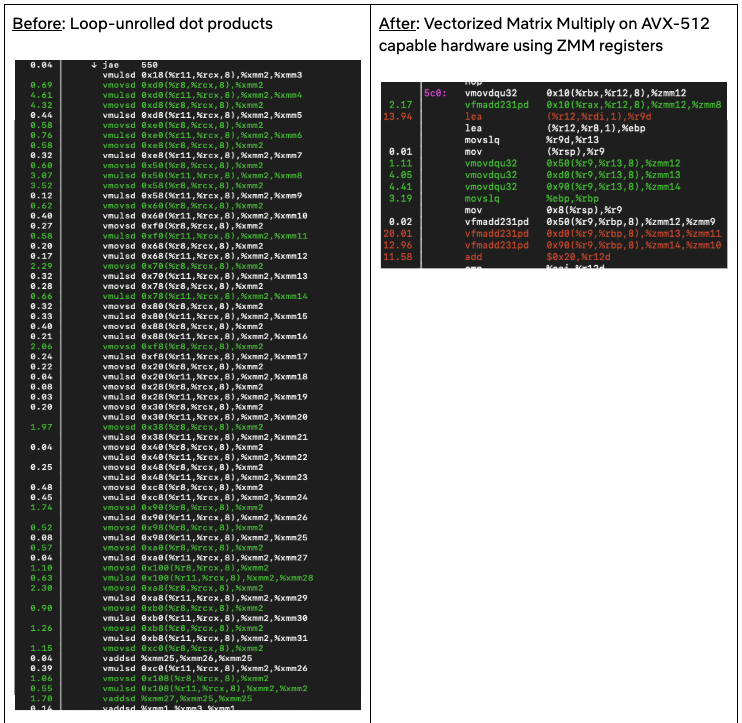
At the function operator level, we saw the CPU drop from the initial 7.5% to a merely ~1% with the optimization in place. At the assembly level, the shift was clear: from loop-unrolled scalar dot products to a vectorized matrix multiply on AVX-512 hardware.

Assembly snippet from batchEncode

Closing Thoughts

This optimization ended up being less about finding the “fastest library” and more about getting the fundamentals right: choosing the right computation shape, keeping data layout cache-friendly, and avoiding overheads that can erase theoretical wins. Once those pieces were in place, the JDK Vector API was a great fit, as it let us express SIMD-style math in pure Java, without JNI, while still keeping a safe fallback path. Another bonus was the low developer overhead: compared to lower-level approaches, the Vector API let us replace a much larger, more complex implementation with a relatively small amount of readable Java code, which made it easier to review, maintain, and iterate on.

Have you tried the Vector API in a real service yet? I’d love to hear what workloads it helped (or didn’t), and what you learned about benchmarking and rollout in production.

Special thanks to Jason Koch, Patrick Strawderman, Daniel Huang, Fan Yang, and the Performance Engineering team at Netflix


Optimizing Recommendation Systems with JDK’s Vector API was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Amazon Managed Service for Apache Flink application lifecycle management with Terraform 

Post Syndicated from Felix John original https://aws.amazon.com/blogs/big-data/amazon-managed-service-for-apache-flink-application-lifecycle-management-with-terraform/

In this post, you’ll learn how to use Terraform to automate and streamline your Apache Flink application lifecycle management on Amazon Managed Service for Apache Flink. We’ll walk you through the complete lifecycle including deployment, updates, scaling, and troubleshooting common issues.

Managing Apache Flink applications through their entire lifecycle from initial deployment to scaling or updating can be complex and error-prone when done manually. Teams often struggle with inconsistent deployments across environments, difficulty tracking configuration changes over time, and complex rollback procedures when issues arise.

Infrastructure as Code (IaC) addresses these challenges by treating infrastructure configuration as code that can be versioned, tested, and automated. While there are different IaC tools available including AWS CloudFormation or AWS Cloud Development Kit (AWS CDK), we focus on HashiCorp Terraform to automate the complete lifecycle management of Apache Flink applications on Amazon Managed Service for Apache Flink.

Managed Service for Apache Flink allows you to run Apache Flink jobs at scale without worrying about managing clusters and provisioning resources. You can focus on developing your Apache Flink using your Integrated Development Environment (IDE) of choice, building and packaging the application using standard build and CI/CD tools. Once your application is packaged and uploaded to Amazon S3, you can deploy and run it with a serverless experience.

While you can control your Managed Service for Apache Flink applications directly using the AWS Console, CLI, or SDKs, Terraform provides key advantages such as version control of your application configuration, consistency across environments, and seamless CI/CD integration. This post builds upon our two-part blog series “Deep dive into the Amazon Managed Service for Apache Flink application lifecycle – Part 1” and “Part 2” that discusses the general lifecycle concepts of Apache Flink applications.

We use the sample code published on the GitHub repository to demonstrate the lifecycle management. Note that this is not a production-ready solution.

Setting up your Terraform environment

Before you can manage your Apache Flink applications with Terraform, you need to set up your execution environment. In this section, we’ll cover how to configure Terraform state management and credential handling. The Terraform AWS provider supports Managed Service for Apache Flink through the aws_kinesis_analyticsv2_application resource (using the legacy name “Kinesis Analytics V2“).

Terraform state management

Terraform uses a state file to track the resources it manages. In Terraform, storing the state file in Amazon S3 is a best practice for teams working collaboratively because it provides a centralised, durable, and secure location for tracking infrastructure changes. However, since multiple engineers or CI/CD pipelines may run Terraform simultaneously, state locking is essential to prevent race conditions where concurrent executions could corrupt the state. S3 as backend is commonly used for state storage and locking, ensuring that only one Terraform process can modify the state at a time, thus maintaining infrastructure consistency and avoiding deployment conflicts.

Passing credentials

To run Terraform inside a Docker container while ensuring that it has access to the necessary AWS credentials and infrastructure code, we follow a structured approach. This process involves exporting AWS credentials, mounting required directories, and executing Terraform commands inside a Docker container. Let’s break this down step by step. Before running Terraform, we need to make sure that our Docker container has access to the required AWS credentials. Since we are using temporary credentials, we generate them using the AWS CLI with the following command:

aws configure export-credentials --profile $AWS_PROFILE --format env-no-export > .env.docker

This command does the following:

  • It exports AWS credentials from a specific AWS profile ($AWS_PROFILE).
  • The credentials are saved in .env.docker in a format suitable for Docker.
  • The --format env-no-export option displays credentials as non-exported shell variables

This file (.env.docker) will later be used to pass credentials into the Docker container

Running Terraform in Docker

Running Terraform inside a Docker container provides a consistent, portable, and isolated environment for managing infrastructure without requiring Terraform to be installed directly on the local machine. This approach ensures that Terraform runs in a controlled environment, reducing dependency conflicts and improving security. To execute Terraform within a Docker container, we use a docker run command that mounts the necessary directories and passes AWS credentials, allowing Terraform to apply infrastructure changes seamlessly.

The Terraform configuration files are stored in a local terraform folder, which is virtually attached to the container using the -v flag. This allows the containerised Terraform instance to access and modify infrastructure code as if it were running locally.

To run Terraform in Docker, the following command is executed:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

Breaking down this command step by step:

  • --env-file .env.docker provides the AWS credentials required for Terraform to authenticate.
  • --rm -it runs the container interactively and is removed after execution to prevent clutter.
  • -v ./terraform:/home/flink-project/terraform mounts the Terraform directory into the container, making the configuration files accessible.
  • -v ./build.sh:/home/flink-project/build.sh mounts the build.sh script, which contains the logic to build JAR file for flink and execute Terraform commands.
  • msf-terraform is the Docker image used, which has Terraform pre-installed.
  • bash build.sh apply runs the build.sh script inside the container, passing apply as an argument to trigger the Terraform apply process.

Inside the container, build.sh typically includes commands such as terraform init to initialise the Terraform working directory and terraform apply to apply infrastructure changes. Since the Terraform execution happens entirely within the container, there is no need to install Terraform locally, and the process remains consistent across different systems. This method is particularly beneficial for teams working in collaborative environments, as it standardises Terraform execution and allows for reproducibility across development, staging, and production environments.

Managing application lifecycle with Terraform

In this section, we walk through each phase of the Apache Flink application lifecycle and understand how you can implement these operations using Terraform. While these operations are usually fully automated as part of a CI/CD pipeline, you will execute the individual steps manually from the command line for demonstration purposes. There are many ways to run Terraform depending on your organization’s tooling and infrastructure setup, but for this demonstration, we run Terraform in a container alongside the application build to simplify dependency management. In real-world scenarios, you would typically have separate CI/CD stages for building your application and deploying with Terraform, with distinct configurations for each environment. Since every organization has different CI/CD tooling and approaches, we keep these implementation details out of scope and focus on the core Terraform operations.

For a comprehensive deep dive into Apache Flink application lifecycle operations, refer to our previous two-part blog series.

Create and start a new application

To get started you want to create your Apache Flink application running on Managed Service for Apache Flink. You should execute the following Docker command:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This command will complete the following operations by executing the bash script build.sh:

  1. Building the Java ARchive (JAR) file from your Apache Flink application
  2. Uploading the JAR file to S3
  3. Setting the config variables for your Apache Flink application in terraform/config.tfvars.json
  4. Create and deploy the Apache Flink application to Managed Service for Apache Flink using terraform apply

Terraform fully covers this operation. You can check the running Apache Flink application using AWS CLI or inside the Managed Apache Flink Console after Terraform completes with Apply Complete! Terraform is expecting the Apache Flink artifact, i.e. the JAR file to be packaged and copied to S3. This operation is usually part of the CI/CD pipeline and executed before invoking the terraform apply. Here, the operation is specified in the build.sh script.

Deploy code change to an application

You have successfully created and started the Flink application. However, you realize that you have to make a change to the Flink application code. Let’s make a code change to the application code in flink/ and see how to build and deploy it. After making the necessary changes, you simply have to run the following Docker command again that builds the JAR file, uploads it to S3 and deploys the Apache Flink application using Terraform:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This phase of the lifecycle is fully supported by Terraform as long as both applications are state compatible, meaning that the operators of the upgraded Apache Flink application are able to restore the state from the snapshot that is taken from the old application version, before Managed Service for Apache Flink stops and deploys the change. For example, removing a stateful operator without enabling the allowNonRestoredState flag or changing an operator’s UID could prevent the new application from restoring from the snapshot. For more information on state compatibility, refer to Upgrading Applications and Flink Versions. For an example of state incompatibility, and strategies for handling state incompatibility, refer to Introducing the new Amazon Kinesis source connector for Apache Flink.

When deploying a code change goes wrong – A problem prevents the application code from being deployed

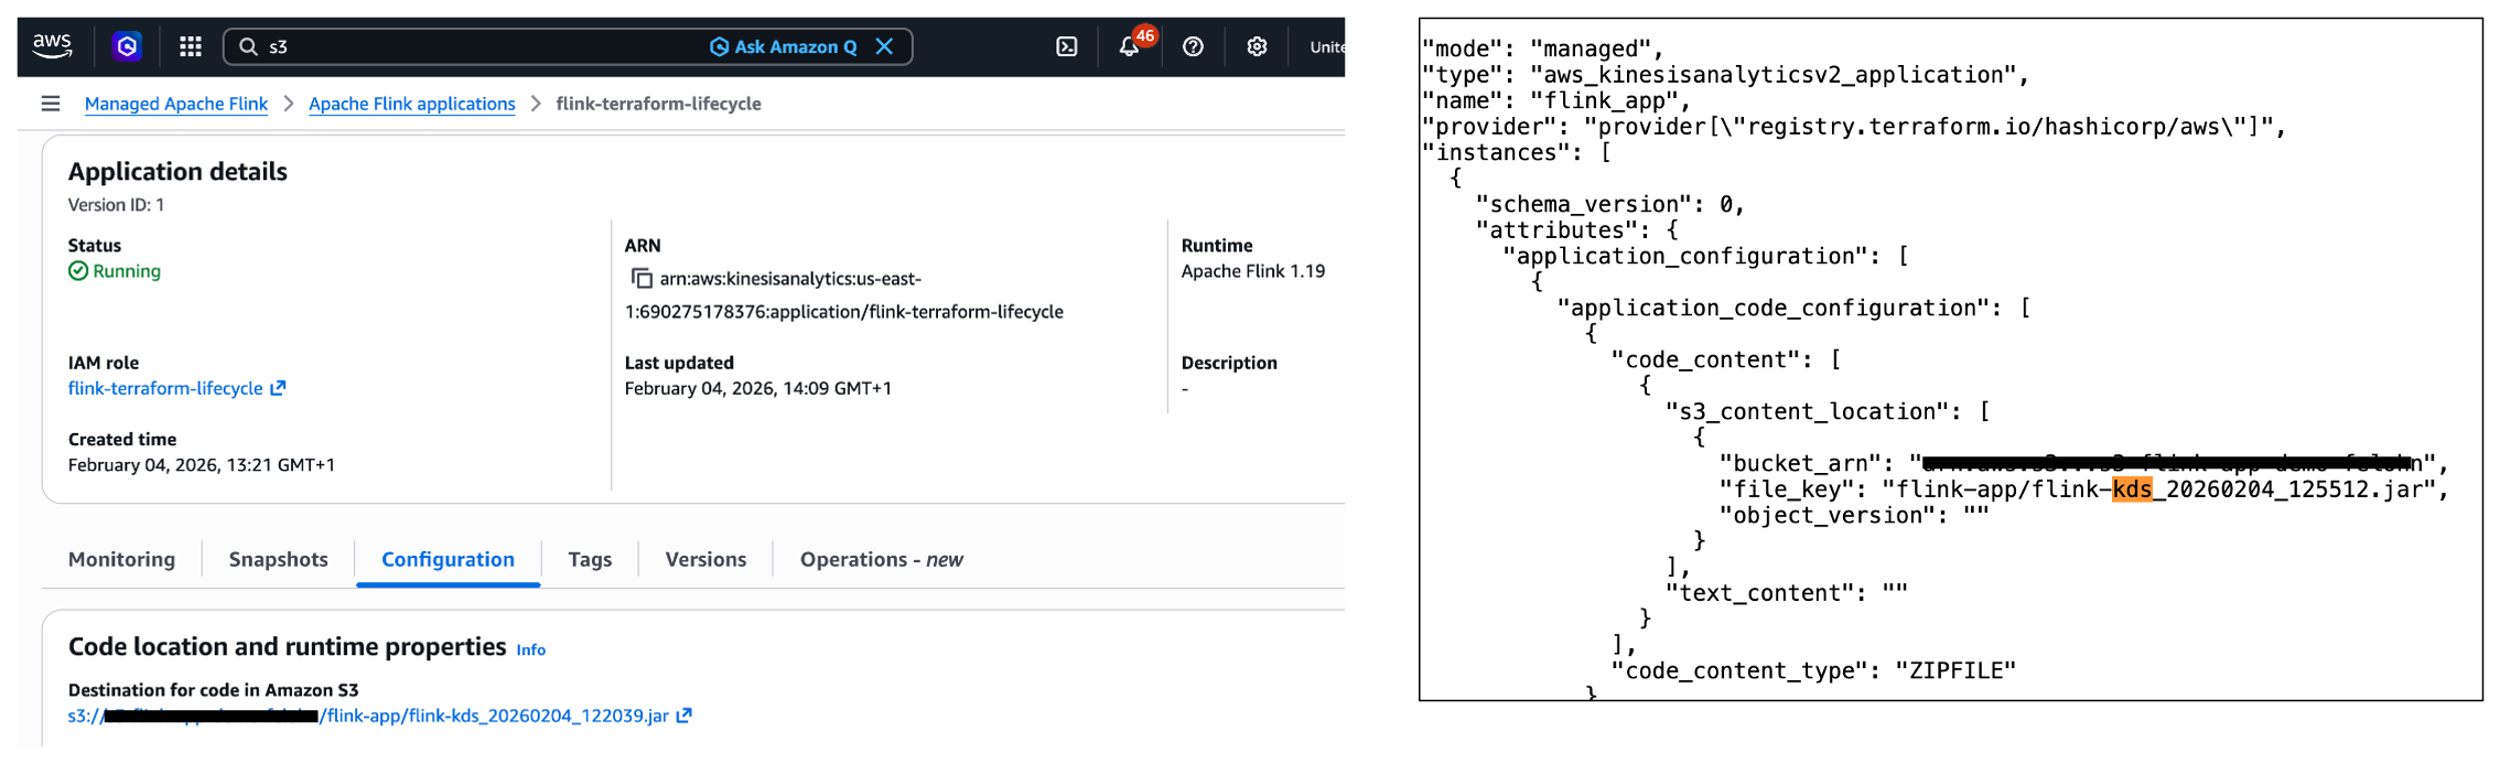
You also need to be careful with deploying code changes that contain bugs preventing the Apache Flink job from starting. For more information, refer to failure mode (a) – a problem prevents the application code from being deployed under When starting or updating the application goes wrong. For instance, this can be simulated by setting the mainClass in flink/pom.xml mistakenly to com.amazonaws.services.msf.WrongJob. Similar to before you build the JAR, upload it and run the terraform apply by running the Docker command from above. However, Terraform now fails to correctly apply the changes and throws an error message as the Apache Flink application fails to correctly update. Finally, the application status moves to READY.

Error message from terminal

To remedy the issue, you have to change the value of mainClass back to the original one and deploy the changes to Managed Service for Apache Flink. The Apache Flink application remains in READY status and doesn’t start automatically, as this was its state before applying the fix. Note that Terraform does not try to start the application when you deploy a change. You will have to manually start the Flink application using the AWS CLI or through the Managed Apache Flink Console.

As detailed in Part 2 of the companion blog, there is a second failure scenario where the application starts successfully, but the job becomes stuck in a continuous fail-and-restart loop. A code change can also cause this failure mode. We will cover the second error scenario when we cover deploying configuration changes.

Manual rollback application code to previous application code

As part of the lifecycle management of your Apache Flink application, you may need to explicitly rollback to a previous running application version. This is particularly useful when a newly deployed application version with application code changes exhibits unexpected behaviour and you want to explicitly rollback the application. Currently, Terraform does not support explicit rollbacks of your Apache Flink application running in Managed Service for Apache Flink. You will have to resort to therollbackApplication API through the AWS CLI or the Managed Service for Apache Flink Console to revert the application to the previous running version.

When you perform the explicit rollback, Terraform will initially not be aware of the changes. More specifically, the S3 path to the JAR file in the Managed Service for Apache Flink service (see left part of the image below) is different to the S3 path denoted in the terraform.tfstate file stored in Amazon S3 (see the right part of the image below). Fortunately, Terraform will always perform refreshing actions that include reading the current settings from all managed remote objects and updating the Terraform state to match as part of creating a plan in both terraform plan and terraform apply commands.

Terraform State vs. MSF State

In summary, while you can not perform a manual rollback using Terraform, Terraform will automatically refresh the state when deploying a change using terraform apply.

Deploy config change to application

You have already made changes to the application code of your Apache Flink application. What about making changes to the config of the application, e.g., changing runtime parameters? Imagine you want to change the application logging level of your running Apache Flink application. To change the logging level from ERROR to INFO, you have to change the value for flink_app_monitoring_metrics_level in the terraform/config.tfvars.json to INFO. To deploy the config changes, you need to run the docker run command again as done in the previous sections. This scenario works as expected and is fully covered by Terraform.

What happens when the Apache Flink application deploys successfully but fails and restarts during execution? For more information, please refer to failure mode (b) – the application is started, the job is stuck in a fail-and-restart loop under When starting or updating the application goes wrong. Note that this failure mode can happen when making code changes as well.

When deploying config change goes wrong – The application is started, the job is stuck in a fail-and-restart loop

In the following example, we apply a wrong configuration change preventing the Kinesis connector from initialising correctly, ultimately putting the job in a fail-and-restart loop. To simulate this failure scenario, you’ll need to modify the Kinesis stream configuration by changing the stream name to a non-existent one. This change is made in the terraform/config.tfvars.json file, specifically altering the stream.name value under flink_app_environment_variables. When you deploy with this invalid configuration, the initial deployment will appear successful, showing an Apply Complete! message. The Flink application status will also show as RUNNING. However, the actual behaviour reveals problems. If you check the Flink Dashboard, you’ll see the application is continuously failing and restarting. Also, you will see a warning message about the application requiring attention in the AWS Console.

Problem message within the MSF Console

As detailed in the section Monitoring Apache Flink application operations in the companion blog (part 2), you can monitor the FullRestarts metric to detect the fail-and-restart loop.

Reverting the changes made to the environment variable and deploying the changes will result in Terraform showing the following error message: Failed to take snapshot for the application flink-terraform-lifecycle at this moment. The application is currently experiencing downtime.

Error message 2 from terminal

You have to force-stop without a snapshot and restart the application with a snapshot to get your Flink application back to a properly functioning state. You should constantly monitor the application state of your Apache Flink application to detect any issues.

Other common operations

Manually scaling the application

Another common operation in the lifecycle of your Apache Flink application is scaling the application up or down by adjusting the parallelism. This operation changes the number of Kinesis Processing Units (KPUs) allocated to your application. Let’s look at two different scaling scenarios and how they are handled by Terraform.

In the first scenario, you want to change the parallelism of your running Apache Flink application within the default parallelism quota. To do this, you need to modify the value for flink_app_parallelism in the terraform/config.tfvars.json file. After updating the parallelism value, you deploy the changes by running the Docker command as done in the previous sections:

docker run --env-file .env.docker --rm -it \
-v ./flink:/home/flink-project/flink \
-v ./terraform:/home/flink-project/terraform \
-v ./build.sh:/home/flink-project/build.sh \
msf-terraform bash build.sh apply

This scenario works as expected and is fully covered by Terraform. The application will be updated with the new parallelism setting, and Managed Service for Apache Flink will adjust the allocated KPUs accordingly. Note that there is a default quota of 64 KPUs for a single Managed Service for Apache Flink application, which must be raised proactively via a quota increase request if you need to scale your Managed Service for Apache Flink application beyond 64 KPUs. For more information, refer to Managed Service for Apache Flink quota.

Less common change deployments which require special handling In this section we analyze some less common change deployment scenarios which require some special handling.

Deploy code change that removes an operator

Removing an operator from your Apache Flink application requires special consideration, particularly regarding state management. When you remove an operator, the state from that operator still exists in the latest snapshot, but there’s no longer a corresponding operator to restore it. Let’s take a closer look at this scenario and understand how you can handle it properly. First, you need to make sure that the parameter AllowNonRestoredState is set to True. This parameter specifies whether the runtime is allowed to skip a state that cannot be mapped to the new program, when restoring from a snapshot. Allowing non-restored state is required to successfully update an Apache Flink application when you dropped an operator. To enable the AllowNonRestoredState, you need to set the configuration value for flink_app_allow_non_restored_state to true in terraform/config.tfvars.json. Then, you can go ahead and remove an operator: For example, you can directly have the sourceStream write to the sink connector in flink/src/main/java/com/amazonaws/services/msf/StreamingJob.java. Change code line 146 from windowedStream.sinkTo(sink).uid("kinesis-sink")to sourceStream.sinkTo(sink).uid("kinesis-sink"). Make sure that you have commented out the entire windowedStream code block (lines 103 to 140).

This change will remove the windowed computation and directly connect the source stream to the sink, effectively removing the stateful operation. After removing the operator from your Flink application code, you deploy the changes using the Docker command as previously done. However, the deployment fails with the following error message: Could not execute application. As a result, the Apache Flink application moves to the READY state. To recover from this situation, you need to restart the Apache Flink application using the latest snapshot for the application to successfully start and move to RUNNING status. Importantly, you need to make sure that AllowNonRestoredState is enabled. Otherwise, the application will fail to start as it cannot restore the state for the removed operator.

Deploy change that breaks state compatibility with system rollback enabled

During the lifecycle management of your Apache Flink application, you might encounter scenarios where code changes break state compatibility. This typically happens when you modify stateful operators in ways that prevent them from restoring their state from previous snapshots.

A common example of breaking state compatibility is changing the UID of a stateful operator (such as an aggregation or windowing operator) in your application code. To safeguard against such breaking changes, you can enable the automatic system rollback feature in Managed Service for Apache Flink as described in the subsection Rollback under Lifecycle of an application in Managed Service for Apache Flink previously. This feature is disabled by default and can be enabled using the AWS Management Console or invoking the UpdateApplication API operation. There is no way in Terraform to enable system rollback.

Next, let’s demonstrate this by breaking the state compatibility of your Apache Flink application by changing the UID of a stateful operator, e.g., the string windowed-avg-price in line 140 of flink/src/main/java/com/amazonaws/services/msf/StreamingJob.java to windowed-avg-price-v2 and deploy the changes as before. You will encounter the following error:

Error: waiting for Kinesis Analytics v2 Application (flink-terraform-lifecycle) operation (*) success: unexpected state ‘FAILED’, wanted target ‘SUCCESSFUL’. last error: org.apache.flink.runtime.rest.handler.RestHandlerException: Could not execute application.

At this point, Managed Service for Apache Flink automatically rolls back the application to the previous snapshot with the previous JAR file, maintaining your application’s availability as you have enabled system-rollback capability. Terraform will initially be not aware of the performed rollback. Fortunately, as we have already witnessed in subsection Manual rollback application code to previous application code, Terraform will automatically refresh the state when we change UID to the previous value and deploy the changes.

In-place upgrade of Apache Flink runtime version

Managed Service for Apache Flink supports in-place upgrade to new Flink runtime versions. See the documentation for more details. Updating the application dependencies and any required code changes is a responsibility of the user. Once you have updated the code artifact, the service is able to upgrade the runtime of your running application in-place, without data loss. Let’s examine how Terraform handles Flink version upgrades.

To upgrade your Apache Flink application from version 1.19.1 to 1.20, you need to:

  1. Update the Flink dependencies in your flink/pom.xml to version 1.20.0 (flink.version to 1.20.1 and flink.connector.version to 5.0.0-1.20 in <properties>)
  2. Update the flink_app_runtime_environment to FLINK-1_20 in terraform/config.tfvars.json
  3. Build and deploy the changes using the familiar docker run command

Terraform successfully performs an in-place upgrade of your Flink application. You will receive the following message: Apply complete! Resources: 0 added, 1 changed, 0 destroyed.

Operations currently not supported by Terraform

Let’s take a closer look at operations that are currently not supported by Terraform.

Starting or stopping the application without any configuration change

Terraform provides the start_application parameter, indicating whether to start or stop the application. You can set this parameter using flink_app_start in config.tfvars.json to stop your running Apache Flink application. However, this will only work if the current configuration value is set to true. In other words, Terraform only responds to the change in the parameter value, not the absolute value itself. After Terraform applies this change, your Apache Flink application will stop and its application status will move to READY. Similarly, restarting the application requires changing the flink_app_start value back to true, but this will only take effect if the current configuration value is false. Terraform will then restart your application, moving it back to the RUNNING state.

In summary, you cannot start or stop your Apache Flink application without making any configuration change in Terraform. You have to use AWS CLI, AWS SDK or AWS Console to start or stop your application.

Restarting application from an older snapshot or no snapshot without any configuration change

Similar to the previous section, Terraform requires an actual configuration change of application_restore_type to trigger a restart with different snapshot settings. Simply reapplying the same configuration values won’t initiate a restart from a different snapshot or no snapshot. You have to use AWS CLI, AWS SDK or AWS Console to restart your application from an older snapshot.

Performing rollback triggered manually or by system-rollback feature

Terraform does not support performing a manual rollback nor automatic system rollback. In addition, Terraform will also not be aware when such a rollback is taking place. The state information will be outdated, e.g. S3 path information. However, Terraform automatically performs refreshing actions to read settings from all managed remote objects and updates the Terraform state to match. Consequently, you can have Terraform refresh the Terraform state by successfully running a terraform apply command.

Conclusion

In this post, we demonstrated how to use Terraform to automate the lifecycle management of your Apache Flink applications on Managed Service for Apache Flink. We walked through fundamental operations including creating, updating, and scaling applications, explored how Terraform handles various failure scenarios and examined advanced scenarios such as removing operators and performing in-place runtime upgrades. We also identified operations that are currently not supported by Terraform.

For more information, see Run a Managed Service for Apache Flink application and our two-part blog on Deep dive into the Amazon Managed Service for Apache Flink application lifecycle.


Felix John

Felix John

Felix is a Global Solutions Architect and data & AI expert at AWS, based out of Germany. He focuses on supporting AWS’ strategic global automotive & manufacturing customers on their cloud journey.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Building a scalable code modernization solution with AWS Transform custom

Post Syndicated from Dinesh Prabakaran original https://aws.amazon.com/blogs/devops/building-a-scalable-code-modernization-solution-with-aws-transform-custom/

Introduction

Software maintenance and modernization is a critical challenge for enterprises managing hundreds or thousands of repositories. Whether upgrading Java versions, migrating to new AWS SDKs, or modernizing frameworks, the scale of transformation work can be overwhelming. AWS Transform custom uses agentic AI to perform large-scale modernization of software, code, libraries, and frameworks to reduce technical debt. It handles diverse scenarios including language version upgrades, API and service migrations, framework upgrades and migrations, code refactoring, and organization-specific transformations. Through continual learning, the agent improves from every execution and developer feedback, delivering high-quality, repeatable transformations without requiring specialized automation expertise.

Organizations need to run transformations using AWS Transform custom concurrently across their entire code estate to meet aggressive modernization timelines and compliance deadlines. Running it at enterprise scale requires a solution to process repositories in parallel, in a controlled remote cloud environment, manage credentials securely, and provide visibility into transformation progress. Today, we’re introducing an open-source solution that brings production-grade scalability, reliability, and monitoring to AWS Transform custom. This infrastructure enables you to run transformations on thousands of repositories in parallel using AWS Batch and AWS Fargate, with REST API access for programmatic control and comprehensive Amazon CloudWatch monitoring.

Requirements for Enterprise-Scale Code Modernization

AWS Transform custom provides powerful AI-driven code transformation capabilities through its CLI. To effectively scale transformations across enterprise codebases, organizations need:

Scale: Ability to run transformations on 1000+ repositories concurrently rather than one-by-one
Infrastructure: Dedicated compute resources for long-running transformations beyond developers’ laptops
API Access: REST API for programmatic orchestration and seamless integration with CI/CD pipelines
Monitoring: Centralized visibility into transformation progress and status across multiple repositories
Reliability: Automatic retries, secure credential management, and built-in fault tolerance

The Solution: Batch Infrastructure with REST API

This solution provides complete, production-ready infrastructure that addresses these challenges:

Core Capabilities

  • Scalable Batch Processing Run transformations on thousands of repositories in parallel using AWS Batch with Fargate. The default configuration (256 max vCPUs, 2 vCPUs per job) supports up to 128 concurrent jobs, with automatic queuing and resource management. The compute environment scales based on your needs and Fargate service quotas.
  • REST API for Programmatic Access Seven API endpoints provide complete job lifecycle management, enabling you to submit single jobs or bulk batches of thousands in one request. The API offers real-time status tracking and progress monitoring, with Amazon Identity and access Management (IAM) authentication ensuring secure access to transformation operations.
  • Multi-Language Container The solution includes a container supporting Java (8, 11, 17, 21), Python (3.8-3.13), and Node.js (16-24) with all build tools pre-installed, including Maven, Gradle, npm, and yarn. The AWS Transform CLI and AWS CLI v2 are bundled in. The container is fully extensible for custom requirements—you can add your own libraries, languages, or tools by customizing the Dockerfile to meet their specific needs
  • Enterprise-Grade Reliability Automatic IAM credential management eliminates long-lived keys, with credentials auto-refreshing every 45 minutes for jobs up to 12 hours. The system includes automatic retries for transient failures (default: 3 attempts), with configurable timeout and retry settings to match your transformation complexity.
  • Comprehensive Monitoring A CloudWatch dashboard provides job tracking with success and failure rates, trends over time, and API and Lambda health metrics. Real-time log streaming enables you to monitor transformation progress and quickly diagnose issues.

Architecture

The solution uses a serverless architecture built on AWS managed services:

AWS Transform custom Batch solution architecture

Key Components:

  • API Gateway: REST API with IAM authentication
  • Lambda Functions: Job orchestration, status tracking, bulk submission
  • AWS Batch: Job queue and compute environment management
  • Fargate: Serverless container execution (no EC2 to manage)
  • S3: Source code input and transformation results output
  • CloudWatch: Logs, metrics, and operational dashboard

Getting Started

Prerequisites

Before deploying, ensure you have:

  • AWS Account with appropriate IAM permissions (ECR, S3, IAM, Batch, Lambda, API Gateway, CloudWatch)
  • AWS CLI v2 configured with credentials or AWS SSO login
  • Docker installed and running
  • Git for cloning the repository
  • Node.js 18+ and AWS CDK (for CDK deployment)
  • Python3for testing the APIs

Deployment Options

Option 1: CDK Deployment (Recommended)

Step 1: Clone the Repository

git clone https://github.com/aws-samples/aws-transform-custom-samples.git

cd aws-transform-custom-samples/scaled-execution-containers

Step 2: Set Environment Variables

export AWS_ACCOUNT_ID=$(aws sts get-caller-identity --query Account --output text)
export CDK_DEFAULT_ACCOUNT=$AWS_ACCOUNT_ID
export CDK_DEFAULT_REGION=us-east-1

Step 3: Verify prerequisites

This checks that Docker is installed and running, AWS CLI v2 is configured with credentials, Git is available, and your AWS account has the required VPC and public subnets.

cd deployment
chmod +x *.sh
./check-prereqs.sh

Step 4: Set up IAM Permissions (Optional, but recommended)

Generate a least-privilege IAM policy instead of using broad permissions:

./generate-custom-policy.sh

This creates iam-custom-policy.json with minimum permissions scoped to your specific resources.

Create and attach the policy:

aws iam create-policy \
  --policy-name ATXCustomDeploymentPolicy \
  --policy-document file://iam-custom-policy.json
aws iam attach-user-policy \
  --user-name YOUR_USERNAME \
  --policy-arn arn:aws:iam::$(aws sts get-caller-identity --query Account --output text):policy/ATXCustomDeploymentPolicy

Note: If you have administrator access, you can skip this step and proceed directly to deployment.

Step 5: Deploy with CDK (One Command Does Everything!)

cd ../cdk
chmod +x *.sh
./deploy.sh

Time: 20-25 minutes (all resources)

What CDK Does Automatically:

  1. Builds Docker image from Dockerfile
  2. Pushes image to ECR
  3. Creates all AWS resources
  4. Configures everything

What Gets Deployed:

  • ECR repository with Docker image
  • S3 buckets (output, source)
  • IAM roles with least-privilege
  • AWS Batch infrastructure (Fargate)
  • 7 Lambda functions
  • API Gateway REST API
  • CloudWatch logs and dashboard

See cdk/README.md for detailed instructions and configuration options.

Step 6: Get Your API Endpoint

After deployment completes, retrieve the API endpoint URL:

export API_ENDPOINT=$(aws cloudformation describe-stacks \
  --stack-name AtxApiStack \
  --query 'Stacks[0].Outputs[?OutputKey==`ApiEndpoint`].OutputValue' \
  --output text)

echo "API Endpoint: $API_ENDPOINT"

This endpoint is used in all subsequent API calls.

Option 2: Bash Scripts (Alternative)

If you prefer manual control over each deployment step or need to customize individual components, use the bash script deployment. See deployment/README.md for the complete 3-step process with detailed explanations of what each script deploys.

Using the Solution

Single Job Submission

Quick test: Run cd ../test && ./test-apis.sh to validate all API endpoints (MCP, transformations, bulk jobs, campaigns).

Submit a Python version upgrade transformation:

cd ..
python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs" \
  --data '{
    "source": "https://github.com/venuvasu/todoapilambda",
    "command": "atx custom def exec -n AWS/python-version-upgrade -p /source/todoapilambda -c noop --configuration \"validationCommands=pytest,additionalPlanContext=The target Python version to upgrade to is Python 3.13. Python 3.13 is already installed at /usr/bin/python3.13\" -x -t"
  }'

This API call triggers a Python version upgrade transformation on the todoapilambda public git repository. The transformation uses the AWS Managed transformation to upgrade from the current Python version to Python 3.13. The configuration parameter specifies additional validation command to be run and plan context to specifies the location of python 3.13 installation in the container and the target version. The -x flag is for non-interactive mode of the transformation , and -t flag is to trust all tools for this transformation.

API returns a job ID for tracking. Job names are auto-generated from the source repository and transformation type.

See api/README.md for complete API documentation with examples for Java, Node.js, and other transformations.

Bulk Job Submission

Transform multiple repositories in a single API call:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs/batch" \
  --data '{
    "batchName": "codebase-analysis-2025",
    "jobs": [
      {"source": "https://github.com/spring-projects/spring-petclinic", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/spring-petclinic -x -t"},
      {"source": "https://github.com/venuvasu/todoapilambda", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/todoapilambda -x -t"},
      {"source": "https://github.com/venuvasu/toapilambdanode16", "command": "atx custom def exec -n AWS/early-access-comprehensive-codebase-analysis -p /source/toapilambdanode16 -x -t"}
    ]
  }'

This API call triggers a deep static analysis of the codebase to generate hierarchical, cross-referenced documentation for three open source repositories in parallel. The transformation uses the AWS Managed transformation to generate behavioral analysis, architectural documentation, and business intelligence extraction to create a comprehensive knowledge base organized for maximum usability and navigation.

The API submits these jobs in a async manner. i.e the API returns a batch id upon submitting these jobs to AWS Batch. Then you can monitor the progress as specified below.

See api/README.md for status checking, MCP configuration, and other API endpoints.

Monitoring Progress

Check batch status:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --method GET \
  --path "/jobs/batch/BATCH_ID"

Response shows real-time progress:

{
  "status": "RUNNING",
  "progress": 45.5,
  "totalJobs": 1000,
  "statusCounts": {
    "RUNNING": 195,
    "SUCCEEDED": 432,
    "FAILED": 23
  }
}

Viewing Results

After a job completes, the results are stored in your S3 output bucket.

S3 Output Structure:

Results are organized by job name and conversation ID:

s3://atx-custom-output-{account-id}/
└── transformations/
    └── {job-name}/                           # e.g., guava-early-access-comprehensive-codebase-analysis
        └── {timestamp}{conversation-id}/     # e.g., 20251227_051626_8f344f5f
            ├── code/                         # Full source code + transformed changes
            └── logs/                         # Execution logs and artifacts
                └── custom/
                    └── {timestamp}{conversation-id}/
                        └── artifacts/
                            └── validation_summary.md

Validation Summary:

AWS Transform CLI generates a validation summary showing all changes made:

s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/logs/custom/{timestamp}{conversation-id}/artifacts/validation_summary.md

This file contains:

  • Summary of all code changes
  • Files modified, added, or deleted
  • Validation results
  • Transformation statistics

Download Results:

# Download all results for a specific job
aws s3 sync s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/ ./local-results/

# Download just the validation summary
aws s3 cp s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/logs/custom/{timestamp}{conversation-id}/artifacts/validation_summary.md ./

# Download transformed code only
aws s3 sync s3://atx-custom-output-{account-id}/transformations/{job-name}/{timestamp}{conversation-id}/code/ ./transformed-code/

Monitoring and Observability

The solution includes a CloudWatch dashboard with operational metrics:

Job Tracking:

  • Completion rate with hourly trends (completed vs failed)
  • Recent jobs table showing job name, timestamp, last message, and log stream
  • Real-time visibility into job execution

CloudWatch Dashboard screenshot for Job tracking

API and Lambda Health:

  • API Gateway request counts and error rates
  • Lambda invocation metrics per function
  • Performance monitoring (duration by function)

CloudWatch Dashboard screenshot for API and Lambda Health

CloudWatch Logs:

All logs are centralized in CloudWatch Logs (/aws/batch/atx-transform) with real-time streaming.

View logs via AWS CLI:

aws logs tail /aws/batch/atx-transform --follow --region us-east-1

Or use the included utility:

python3 utilities/tail-logs.py JOB_ID --region us-east-1

View in AWS Console: CloudWatch → Log Groups → /aws/batch/atx-transform

Model Context Protocol (MCP) Integration

AWS Transform custom supports Model Context Protocol (MCP) servers to extend the AI agent with additional tools. Configure MCP servers via API:

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/mcp-config" \
  --data '{
    "mcpConfig": {
      "mcpServers": {
        "github": {"command": "npx", "args": ["-y", "@modelcontextprotocol/server-github"]},
        "fetch": {"command": "uvx", "args": ["mcp-server-fetch"]}
      }
    }
  }'

The configuration is stored in S3 and automatically available to all transformations. Test with atx mcp tools to list configured servers.

See api/README.md for status checking, MCP configuration, and other API endpoints.

Customization for Private Repositories

You may need to access private repositories and artifact registries. Extend the base container to add credentials:

To access your private Git repositories or artifact registries during transformations:

Two approaches:

  1. AWS Secrets Manager (RECOMMENDED) – Credentials fetched at runtime, never stored in image
  2. Hardcode in Dockerfile (NOT RECOMMENDED) – For testing only

Steps:

  1. Uncomment placeholders in container/entrypoint.sh (Secrets Manager) or container/Dockerfile (hardcoded)
  2. Redeploy container (see below)

See container/README.md for complete setup instructions, examples, and security best practices.

Redeploying after customization:

If using CDK:

cd cdk && ./deploy.sh

CDK automatically detects Dockerfile changes and rebuilds. If changes aren’t detected, force rebuild:

cd cdk && ./deploy.sh —force

If using bash scripts:

cd deployment
./1-build-and-push.sh --rebuild
./2-deploy-infrastructure.sh

The infrastructure will use your custom container with private repository access. You can also customize the container to add support for additional language versions or entirely new languages based on their specific requirements.

See container/README.md for complete examples.

Note: For automated PR creation and pushing changes back to remote repositories after transformation, you have two options: (1) extend container/entrypoint.sh with git commands using your private credentials (see commented placeholder in the script), or (2) use a custom Transformation definition with MCP configured to connect to GitHub/GitLab for more sophisticated PR workflows.

Campaigns

Central platform teams can create campaigns through the AWS Transform web interface to manage enterprise-wide migration and modernization projects. For instance, to upgrade all repositories from Java 8 to Java 21, teams create a campaign with the Java upgrade transformation definition and target repository list. As developers execute transformations, repositories automatically register with the campaign, enabling you to track progress and monitor across your organization.

Creating a Campaign

  1. Setup Users and Login to AWS Transform web application
  2. Create a Workspace and Create a Job
  3. In the chat, specify the type of the job . For example , “I would like comprehensive code analysis on multiple repos”
  4. Based on your request, AWS Transform will display the list of transformation that matches the criteria, in this case “AWS/early-access-comprehensive-codebase-analysis (Early Access)”
  5. Once you confirm the transformation, AWS Transform will create a campaign and a command to execute for the transformation. You can just copy that command and execute via the API as described below replacing the repo details.
atx custom def exec \
--code-repository-path <path-to-repo> \
--non-interactive \
--trust-all-tools \
--campaign 0d0c7e9f-5cb2-4569-8c81-7878def8e49e \
--repo-name <repo-name> \
--add-repo

Executing the Transformation in a Campaign

python3 utilities/invoke-api.py \
  --endpoint "$API_ENDPOINT" \
  --path "/jobs" \
  --data '{
    "source": "https://github.com/spring-projects/spring-petclinic",
    "command": "atx custom def exec --code-repository-path /source/spring-petclinic --non-interactive --trust-all-tools --campaign 0d0c7e9f-5cb2-4569-8c81-7878def8e49e --repo-name spring-petclinic --add-repo"
  }'

Once this transformation Job is successful, you can view the results and dashboard in Web application as well.

Cleanup

To remove all deployed resources:

CDK Cleanup (Recommended)

cd cdk ./destroy.sh

Bash Scripts Cleanup (Alternate)

cd deployment ./cleanup.sh

This script deletes:

  • AWS Batch resources (compute environment, job queue, job definitions)
  • Lambda functions and API Gateway
  • IAM roles
  • S3 buckets (after emptying)
  • CloudWatch logs and dashboard
  • ECR repository

Conclusion

Enterprise software modernization requires infrastructure that can operate at scale with reliability and observability. This solution provides a production-ready platform for running AWS Transform custom transformations on thousands of repositories concurrently.

By combining AWS Batch’s scalability, Fargate’s serverless compute, and a REST API for programmatic access, you can:

  • Accelerate modernization initiatives
  • Reduce manual effort and human error
  • Gain visibility into transformation progress
  • Integrate with existing DevOps workflows

The code repository is open-source, fully automated, and ready for you to deploy in your AWS account today.

Get started today with AWS Transform custom

About the authors

Profile image for Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Senior Specialist Solutions Architect at AWS, where he leads Generative AI initiatives focused on Amazon Q Developer, Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

Profile image for Dinesh Balaaji Prabakaran

Dinesh Balaaji Prabakaran

Dinesh is a Enterprise Support Lead at AWS who specializes in supporting Independent Software Vendors (ISVs) on their cloud journey. With expertise in AWS Generative AI Services, he helps customers leverage Amazon Q Developer, Kiro, and AWS Transform to accelerate application development and modernization through AI-powered assistance.

Profile image for Brent Everman

Brent Everman

Brent Everman is a Senior Technical Account Manager with AWS, based out of Pittsburgh. He has over 17 years of experience working with enterprise and startup customers. He is passionate about improving the software development experience and specializes in the AWS Next Generation Developer Experience services.

AWS Transform custom: AI-driven Java modernization to reduce tech debt

Post Syndicated from Dinesh Prabakaran original https://aws.amazon.com/blogs/devops/aws-transform-custom-ai-driven-java-modernization-to-reduce-tech-debt/

In today’s rapidly evolving software landscape, maintaining and modernizing Java applications is a critical challenge for many organizations. As new Java versions are released and best practices evolve, the need for efficient code transformation becomes increasingly important. Organizations today face significant challenges when modernizing their Java applications. Legacy codebases often contain outdated patterns, deprecated APIs, and inefficient implementations that hinder performance and maintainability. Traditional manual refactoring approaches are time-consuming, error-prone, and difficult to scale across large codebases. In addition, as developers spend more time on new development and deployment, the volume of technical debt continues to rise, requiring transformation of legacy code at-scale.

AWS Transform custom addresses these challenges through intelligent automation, providing AWS-managed transformations – standardized transformation packages for common scenarios like Java version upgrades. These transformations enable teams to achieve quick wins through standardized, tested transformation patterns that can be executed at scale, bringing significant time and cost savings to customers. In addition, customers can create custom user defined transformations to address technical debt with code transformations across languages, frameworks, and more.

This post explores how to leverage AWS Transform custom’s out-of-the-box transformation for Java upgrades. By the end of this post, you’ll understand how to use these standardized transformations to modernize your Java applications efficiently while maintaining full control over the transformation process.

Introduction to AWS Transform custom

AWS Transform custom uses agentic AI to automate large-scale code modernization, handling language version upgrades, API migrations, framework updates, and organization-specific transformations. Through continual learning, the agent improves from every execution and developer feedback, delivering high-quality, repeatable transformations without requiring specialized automation expertise.

Prerequisites

Before starting your Java modernization journey with AWS Transform custom, ensure you have the necessary development environment, build tools, and AWS Transform custom command line interface (CLI) installed. For detailed prerequisites and setup instructions, refer to the AWS Transform custom Prerequisites Guide.

Understanding the Modernization Scenario

We’ll demonstrate AWS Transform custom using a Movie Service application – a Spring Boot REST API built on Java 8 with Gradle. This represents a typical enterprise modernization challenge with legacy dependencies, outdated patterns, and technical debt.

Leveraging AWS-Managed Transformations

AWS Transform custom focuses on leveraging AWS-managed transformations designed for common modernization tasks like Java version upgrades.

AWS-managed transformations are pre-built, AWS-vetted transformations for common use cases that are ready to use without any additional setup. These transformations provide immediate value with minimal configuration, making them ideal for standard upgrade scenarios.

Understanding AWS Transform custom CLI Capabilities

AWS Transform custom provides a comprehensive command-line interface that enables both interactive and automated transformation workflows:

atx --version                    # Display ATX version
atx --help                       # Display general help
atx custom def list              # List transformation packages
atx                              # Start interactive conversation

For detailed information on all available commands, refer to the AWS Transform custom command reference.

Screenshot of AWS Transform custom interactive mode.
Figure 1:AWS Transform custom interactive mode

Discovering Available Transformations

Use atx custom def list to view all available transformations, including AWS-managed transformations and custom-defined (user-defined) transformations created by your organization. Key AWS-managed transformations include Java/Python/Node.js version upgrades and AWS SDK migrations.

Screenshot of AWS Transform interface displaying categorized lists of AWS Managed transformations and user-defined custom
transformations.
Figure 2: AWS Transform custom lists available AWS Managed and custom-defined (user-defined) transformations

Applying AWS-Managed Transformations

Before applying any transformations, ensure your project is initialized with Git and that all build and test cases are working correctly with Java 8 (Test cases can be skipped when necessary by using the appropriate build command option and instructions to the agent). For Gradle projects, verify that ./gradlew build executes successfully.

The transformation process follows a structured approach:

  1. Ensure Clean Git State:
git status
git add .
git commit -m "Baseline before Java 21 transformation"
  1. Apply Transformation: You can apply transformations using either interactive or direct command modes. In this blog, we will use the interactive mode to walk through the process step-by-step:

Interactive Mode (used in this blog):

First, create a config.json file with your transformation configuration:

{
  "codeRepositoryPath": "/path/to/your/aws-appconfig-java-sample-gradle",
  "transformationName": "AWS/java-version-upgrade",
  "buildCommand": "./gradlew clean build",
  "validationCommands": "build and validate using \"./gradlew clean build\" after transformation to test with java 21",
  "additionalPlanContext": "This is a Java 8 to 21 transformation of a gradle app , also include all dependency migration as well. Use java path /path/to/your/java-8/bin/java and /path/to/your/java-21/bin/java when building before and after transformation. We are using gradle wrapper gradlew, update it if needed for java 21 upgrade. Check for deprecated methods and dependencies and update them."
}

Update the codeRepositoryPath in your config.json to point to your local project directory and update the Java path in additionalPlanContext to match your Java 8 and 21 installation. For more details about configuration files and their parameters, refer to Using Configuration Files.

Then execute the transformation in interactive mode (used for this blog walkthrough):

For Java version upgrade with Gradle using config.json (Interactive Mode):
atx custom def exec -t --configuration file://config.json

Screenshot of AWS Transform interface displaying categorized lists of AWS Managed transformations and user-defined custom transformations.
Figure 3: AWS Transform custom execute a gradle transformation in interactive mode with transformation configuration supplied from config.json

Direct Command Mode (alternative approach): Use this mode for automated CI/CD pipelines or when you want to execute transformations without interactive prompts.

atx custom def exec -x -t --configuration “file://config.json”

Parameter explanation:

--configuration: Specifies the configuration file for interactive mode

-x: Executes the transformation automatically without interactive prompts (direct mode)

-t: Enables test mode for validation during execution (direct mode)

--configuration: Specifies the configuration file path with file://prefix (direct mode)

ATX Execution Command Executing AWS managed Java version upgrade transformation for Gradle project using ATX CLI

  1. Review Transformation Plan: AWS Transform custom analyzes your project based on the configuration provided in config.json and generates a comprehensive transformation plan. This plan details all proposed changes, including:
  • Java version updates: Migration from Java 8 to Java 21 configurations
  • API migration patterns: Automatic updates for deprecated APIs and modern alternatives
  • Framework modernization: Spring Boot version upgrades and compatibility updates
  • Dependency modifications: Updated library versions compatible with Java 21
  • Build system updates: Gradle configuration and plugin changes for Java 21 compatibility
  • Code pattern improvements: Implementation of modern Java features and best practices

We recommend doing a thorough review of the transformation plan to ensure it encompasses all expected updates. The additionalPlanContext in your config.json helps guide the transformation to include dependency migrations and Gradle wrapper updates. If adjustments are needed, provide feedback through the CLI interface.

Additionally, if you want to customize the transformation to target additional changes, for example upgrading additional legacy dependencies contained in the project, you can provide this as feedback when reviewing the transformation plan. AWS Transform custom incorporates all feedback provided to refine the transformation plan before proceeding.

  1. Apply the Transformation: After confirming the transformation plan meets your requirements, type proceed and press Enter. AWS Transform custom executes the transformation according to the approved plan.

The transformation process automatically:

– Creates a new branch and commits the transformed changes in there

– Updates Gradle configuration for Java 21

– Migrates Java EE to Jakarta EE packages (if applicable)

– Updates framework dependencies for Java 21 compatibility

– Applies all necessary code changes

– Updates test cases and testing frameworks for Java 21 compatibility

– Runs comprehensive validation builds

Results of AWS-Managed Transformations

After applying the Java version upgrade transformation, below changes are observed:

Configuration Updates: – Java version: 1.8 → 21 – Spring Boot version upgrades – Gradle plugin and configuration updates – Dependency version modernization

To validate the changes, switch to Java 21 and run ./gradlew build to ensure the transformation was successful, then test the application functionality.

Figure 4: displaying Updated Gradle Configuration Gradle build.gradle showing updated Java 21 configuration and modernized
dependencies
Figure 4: Updated Gradle Configuration Gradle build.gradle showing updated Java 21 configuration and modernized dependencies

Figure 5: Updated code where legacy pattern of raw types usage is transformed to generics
Figure 6: Second example of updated code where legacy pattern of raw types usage is transformed to generics
Figure 7: Updated dependency from javax.security to java.security and uses CertificateFactory to get X509Certificate
Figure 7: Updated dependency from javax.security to java.security and uses CertificateFactory to get X509Certificate
Figure 8: Updated Test cases from junit 4 to junit5

Beyond AWS-Managed Transformations: Custom-Defined Transformations

While AWS-managed transformations provide excellent coverage for standard Java modernization scenarios, there are cases where the available AWS-managed transformations may not address your specific transformation requirements. In such situations, AWS Transform custom enables users to create and test their own organization specific, custom-defined transformation definitions.

When to Create Custom-Defined Transformations

Custom-defined transformations become necessary when AWS-managed transformations don’t cover your specific needs, such as proprietary frameworks, organization-specific coding standards, or complex multi-step migration scenarios.

Creating Custom-Defined Transformations

AWS Transform custom enables teams to develop custom transformations using transformation rules and configuration files. This allows organizations to define transformation logic specific to their requirements, test on sample code, and share validated transformations across teams.

AWS Transform custom’s interactive mode (atx) is particularly beneficial for creating Custom-defined transformations, enabling conversational interaction to iteratively refine requirements and get real-time feedback. Custom-defined transformations provide flexibility to extend AWS Transform custom’s capabilities when AWS-managed transformations don’t meet specific modernization needs.

Continual Learning and Knowledge Items

AWS Transform custom automatically learns from each transformation execution to improve future results. For Java upgrades specifically, the service captures patterns like successful refactoring strategies, common dependency conflicts, and framework compatibility matrices across Java versions. This knowledge feeds back into future transformations, making them more accurate at predicting successful upgrade paths and reducing manual intervention.

Knowledge items are account-specific and remain within your AWS account boundaries. Users can enable or disable continual learning, providing full control over this preference.

Conclusion

In this blog, we demonstrated how AWS Transform custom enables efficient Java application modernization using AWS managed transformations. Starting with a legacy Movie Service application running Java 8 and Spring Boot 2.x, we successfully transformed it to Java 21 with modern dependencies and patterns.

The step-by-step process showed how to establish a baseline, discover available transformations using atx custom def list, and apply transformations through AWS Transform custom’s CLI. The result was a fully modernized application with updated Java versions, Spring Boot upgrades, and modern Java features like enhanced switch expressions and local variable type inference – all achieved in minutes rather than weeks of manual refactoring.

Beyond Java Modernization

Beyond Java modernization, AWS Transform custom’s transformation capabilities extend to other programming languages and frameworks, making it a versatile solution for comprehensive application portfolio modernization across diverse technology stacks. The agent supports diverse transformation use cases including:

  • Version upgrades for Java, Python, and Node.js
  • Runtime and API migrations (AWS SDK v1→v2, Boto2→Boto3)
  • Framework transitions and upgrades
  • Language translations and architectural changes
  • Organization-specific, custom-defined transformations

Through its define once, transform everywhere approach, AWS Transform custom enables organizations to capture and amplify transformation knowledge by defining transformations once and executing repeatable tasks across the entire organization. This reduces knowledge silos and ensures consistent quality regardless of team or project scope.

Getting Started

Ready to modernize your Java applications with AWS Transform custom? Here’s how to begin:

  1. Install AWS Transform custom CLI (atx) using the installation script and verify your environment
  2. Configure AWS credentials with transform-custom:* permissions
  3. Explore available AWS-managed transformations using atx custom def list
  4. Apply transformations to your Java applications using direct execution mode (atx custom def exec) or interactive mode (atx)
  5. Validate results through comprehensive testing with ./gradlew build for Gradle projects
  6. Scale across your application portfolio for consistent modernization

Additional Resources

For detailed setup instructions and documentation, visit:

Start your modernization journey today and experience the power of AI-driven code transformation at scale.

About the authors

Profile image for Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan Vasudevan (Venu) is a Senior Specialist Solutions Architect at AWS, where he leads Generative AI initiatives focused on Amazon Q Developer, Kiro, and AWS Transform. He helps customers adopt and scale AI-powered developer and modernization solutions to accelerate innovation and business outcomes.

Profile image for Dinesh Balaaji Prabakaran

Dinesh Balaaji Prabakaran

Dinesh is a Enterprise Support Lead at AWS who specializes in supporting Independent Software Vendors (ISVs) on their cloud journey. With expertise in AWS Generative AI Services, he helps customers leverage Amazon Q Developer, Kiro, and AWS Transform to accelerate application development and modernization through AI-powered assistance.

Profile image for Sureshkumar Natarajan

Sureshkumar Natarajan

Sureshkumar Natarajan is a Senior Technical Account Manager at AWS, where he supports Enterprise customers in their cloud journey with a focus on Generative AI initiatives. He guides organizations in leveraging Amazon Q Developer, Kiro, and AWS Transform to unlock new capabilities, streamline development workflows, and achieve transformative business results.

Profile image for Anjan Dave

Anjan Dave

Anjan Dave is a Principal Solutions Architect at AWS with over 25 years of IT experience. He specializes in generative AI application modernization, infrastructure scalability, and developer productivity initiatives.
Anjan leads GenAI and modernization strategies across global projects, influencing technology roadmaps for HCM providers through event-driven and microservices architectures. He advocates for integrating Generative AI into the software development lifecycle to automate routine tasks, enabling engineering teams to focus on high-value architectural work.

Automating AWS SDK for Java v1 to v2 Upgrades with AWS Transform

Post Syndicated from Brent Everman original https://aws.amazon.com/blogs/devops/automating-aws-sdk-for-java-v1-to-v2-upgrades-with-aws-transform/

The AWS SDK for Java v2 represents a fundamental shift in how Java applications interact with AWS services, addressing critical security requirements while delivering measurable performance improvements. For organizations still operating on v1, this transition extends beyond a routine version upgrade—it’s a strategic imperative for maintaining secure, efficient cloud operations. With v1 reaching end-of-support on December 31, 2025, organizations face a hard deadline where security vulnerabilities will no longer receive patches, potentially violating compliance frameworks that require current, supported software versions.

Security enhancements alone justify the migration, with v2 implementing advanced credential management, modernized encryption clients, and comprehensive TLS security protocols that v1’s architecture cannot accommodate. Beyond security, v2 delivers architectural improvements through non-blocking I/O operations and modular service clients that reduce application footprint while improving response times.

This blog post demonstrates how to automate AWS SDK for Java v1 to v2 upgrades using AWS Transform custom, enabling organizations to modernize their Java applications efficiently while minimizing manual intervention and potential errors.

AWS Transform custom uses agentic AI to perform large-scale modernization of software, code, libraries, and frameworks to reduce technical debt. It handles diverse scenarios including language version upgrades, API and service migrations, framework upgrades and migrations, code refactoring, and organization-specific transformations.

Prerequisites

Before beginning the transformation process, verify the following requirements:

Solution Overview

The AWS Transform CLI provides AWS-Managed Transformations that are pre-built, AWS-vetted transformations for common use cases that are ready to use without any additional setup. The AWS/java-aws-sdk-v1-to-v2 transformation enables you to upgrade the AWS SDK from v1 to v2 for Java projects. We will use this verified transformation definition to upgrade a sample Java application from AWS SDK for Java v1 to v2.

Step 1: Prepare the Sample Project

Clone the AWS Java sample repository to your local environment:

git clone https://github.com/aws-samples/aws-java-sample
cd aws-java-sample

Step 2: Execute the Transformation

The AWS Transform CLI’s def exec command provides multiple parameters for customizing transformations. View all available options using atx custom def exec --help. For this transformation, execute the following command (replace <path_to_project> with your actual project path):

atx custom def exec -n AWS/java-aws-sdk-v1-to-v2 -p <path_to_project> -t -c "mvn package"

Parameter breakdown:

  • -p: Path to the code repository to transform
  • -n: Name of the transformation definition in the registry
  • -t: Trusts all tools (no tool prompts)
  • -c: Command to run when building repository

Step 3: Provide Additional Guidance

Before AWS Transform generates the transformation plan, it asks if there is specific guidance to take into consideration when generating the plan. For example, some organizations may require or have approved the use of specific versions of libraries. If there are specific requirements like this or guidance you would like to provide, please add it here. For this sample, enter the following prompt that demonstrates how you can specify a specific version of a library that may be needed to meet organizational requirements:

Please utilize version 2.34.0 of software.amazon.awssdk

Step 4: Review the Transformation Plan

AWS Transform analyzes your project and generates a comprehensive transformation plan. This plan details all proposed changes, including:

  • Update Maven dependencies
  • API migration patterns
  • Builder pattern implementations
  • Update exception handling

The transformation plan will be outlined in a plan.json file in the specified directory in the output (Figure 1). We suggest doing a thorough review of the transformation plan to ensure it encapsulates all expected updates. If adjustments are needed, feedback can be provided through the CLI interface. AWS Transform custom incorporates all feedback provided to refine the transformation plan before proceeding.

Transformation plan output

Figure 1: Transformation plan output

Step 5: Apply the Transformation

After confirming the transformation plan meets your requirements, type proceed and press Enter. AWS Transform custom proceeds to the next step and executes the transformation according to the approved plan.

Step 6: Verify Changes

Once the transformation is complete, you can review the validation summary that was written to the validation_summary.md file in the specified directory. After reviewing the summary, we will use our IDE (VS Code in this case, you can use your preferred mechanism) to examine the transformation results.

POM.xml Updates: The AWS SDK dependency upgrades from version 1.9.6 to 2.34.0 (Figure 2), reflecting the version that was specified during the planning phase.

POM.xml Updates

Figure 2: POM.xml Updates

Code Pattern Updates: The S3Sample.java file shown in Figure 3 demonstrates v2’s builder pattern implementation.

Builder pattern updates

Figure 3: Builder pattern updates

Step 7: Build the application

Since the build command was passed as part of the -c parameter, AWS Transform custom will have already verified that the application builds as expected. We will also validate the transformation by building the application via the following command:

mvn clean package

The application should build successfully and you should see a BUILD SUCCESS message.

Step 7: Test the application

Next, we will verify that the application’s functionality is working as expected after the transformation. Configure your AWS credentials and run the application:

aws configure
mvn clean compile exec:java

The application should execute successfully (as seen in Figure 4), demonstrating that core functionality remains intact after the transformation.

Successful application execution logs

Figure 4: Successful application execution

Custom Transformation Definition

While AWS provides managed transformations for modernizing legacy projects, these standard solutions may not always meet an organization’s unique requirements. Although AWS allows customization of these managed transformations through plan context and feedback mechanisms, some scenarios demand custom solutions. This is particularly true when organizations need to:

  1. Upgrade proprietary internal frameworks
  2. Update custom libraries
  3. Manage complex SDK version upgrades
  4. Handle organization-specific code patterns

AWS Transform custom addresses these needs by enabling organizations to create and maintain their own transformation definitions. This capability offers several advantages:

  • Allows organizations to codify their specific modernization requirements
  • Creates reusable transformation patterns
  • Enables consistent application of organizational best practices
  • Facilitates scalable modernization efforts across multiple projects
  • Preserves and leverages institutional knowledge through documented transformations

By defining these custom transformations once, organizations can efficiently execute standardized modernization tasks across their entire codebase, ensuring consistency and reducing manual effort.

Conclusion

The automated transformation from AWS SDK for Java v1 to v2 using the AWS Transform CLI demonstrates how organizations can modernize their Java applications efficiently while maintaining code quality and functionality. This approach eliminates the manual effort traditionally required for SDK migrations, reducing both time investment and the risk of introducing errors during the upgrade process.

Key benefits realized through this automation:

  • Accelerated migration timeline – What typically requires weeks of manual refactoring completes in minutes
  • Consistent transformation patterns – Verified transformations ensure uniform code updates across your entire codebase
  • Reduced human error – Automated pattern recognition and replacement eliminates common migration mistakes
  • Immediate security improvements – Applications gain V2’s enhanced security features without extensive manual intervention

As AWS continues to innovate and enhance AWS SDK for Java v2 with new features and optimizations, maintaining current SDK versions becomes increasingly important. By automating this critical upgrade process, development teams can focus on delivering business value while ensuring their applications leverage the latest AWS capabilities and security enhancements. Get started with AWS Transform custom today to begin your modernization journey, or explore additional AWS-Managed Transformations to address other modernization use cases.

Introducing AWS Lambda native support for Avro and Protobuf formatted Apache Kafka events

Post Syndicated from Julian Wood original https://aws.amazon.com/blogs/compute/introducing-aws-lambda-native-support-for-avro-and-protobuf-formatted-apache-kafka-events/

AWS Lambda now provides native support for Apache Avro and Protocol Buffers (Protobuf) formatted events with Apache Kafka event source mapping (ESM) when using Provisioned Mode. The support allows you to validate your schema with popular schema registries. This allows you to use and filter the more efficient binary event formats and share data using schema in a centralized and consistent way. This blog post shows how you can use Lambda to process Avro and Protobuf formatted events from Kafka topics using schema registry integration.

This new capability works with both Amazon Managed Streaming for Apache Kafka (Amazon MSK), Confluent Cloud and self-managed Kafka clusters. To get started, update your existing Kafka ESM to Provisioned Mode and add schema registry configuration, or create a new ESM in Provisioned Mode with schema registry integration enabled.

Avro and Protobuf

Many organizations use Avro and Protobuf formats with Apache Kafka because these binary serialization formats offer advantages over JSON. They provide 50-80% smaller message sizes, faster serialization and deserialization performance, robust schema evolution capabilities, and strong typing across multiple programming languages.Working with these formats in Lambda functions previously necessitated custom code. Developers needed to implement schema registry clients, handle authentication and caching, write format-specific deserialization logic, and manage schema evolution scenarios.

What’s new

Lambda’s Kafka Event Source Mapping (ESM) now provides built-in integration with AWS Glue Schema Registry, Confluent Cloud Schema Registry, and self-managed Confluent Schema Registry. When you configure schema registry settings for your Kafka ESM, the service automatically validates incoming JSON Schema, Avro, and Protobuf records against their registered schema. This moves complex schema registry integration logic from your application layer to the managed Lambda service.

You can build your function with Kafka’s open-source ConsumerRecords interface using Powertools for AWS Lambda to get your Avro or Protobuf generated business objects directly. Optionally you can specify to get your records in the JSON format, where your function receives clean, validated JSON data regardless of the original serialization format, removing the need for custom deserialization code in your Lambda functions. This also allows you to create Kafka consumers across multiple programming languages.

Powertools for AWS Lambda is a developer toolkit that provides specific support for Java, .NET, Python, and TypeScript, maintaining consistency with existing Kafka development patterns. You can directly access business objects without custom deserialization code.

You can also setup filtering rules to discard irrelevant, JSON, Avro or Protobuf formatted events before function invocations, which can improve processing performance and reduce costs.

How schema validation works

When you configure schema registry integration for your Kafka ESM, you specify the registry endpoint, authentication details, and which event fields (key, value, or both) to validate. The ESM polls your Kafka topics for records as usual but now performs additional processing before invoking your Lambda function.For each incoming event, the ESM extracts the schema ID embedded in the serialized data. It fetches the corresponding schema from your configured registry. This process happens transparently, with schema definitions cached for up to 24 hours to optimize performance. The ESM identifies the format of your events using schema metadata and validates the event structure. It keeps either the original binary data or deserializes it to JSON format based on your customer configuration and sends it to your function for processing.


Figure 1: Kafka processing flow diagram.

The ESM handles schema evolution automatically. When producers begin using new schema versions, the service detects the updated schema IDs and fetches the latest definitions from your registry. This makes sure that your functions always receive properly deserialized data without requiring code changes.

Event record format

As a part of the ESM schema registry configuration, you need to specify Event Record Format, which Lambda uses to deliver validated records to your function. The schema registry configuration supports SOURCE and JSON.

SOURCE preserves the original binary format of the data as a base64-encoded string with producer-appended schema-id removed. This allows direct conversion to Avro or Protobuf objects so that you can use Kafka’s ConsumerRecords interface for a Kafka-like experience. Use this format when working with strongly typed languages or when you need to maintain the full capabilities of Avro or Protobuf schemas. Then, you can use any Avro or Protobuf deserializer to convert raw bytes to your business object. Powertools provides native support for this deserialization.

With JSON, the ESM deserializes the data ready for direct use in languages with native JSON support. Use this when you don’t need to preserve the original binary format or work with generated classes. You can also use Powertools to convert the base64 to your business object. See the documentation for payload formats and deserialization behavior.

If you configure filtering rules, then they operate on the JSON-formatted events after deserialization. This upstream filtering prevents unnecessary Lambda invocations for events that don’t match your processing criteria, directly reducing your compute costs.

Configuration and setup

To use this feature, you must enable Provisioned Mode for your Kafka ESM, which provides the dedicated compute resources needed for schema registry integration.

You can configure the integration through the AWS Management ConsoleAWS Command Line Interface (AWS CLI)AWS Language SDKs, or infrastructure as code (IaC) tools such as the AWS Serverless Application Model (AWS SAM) or AWS Cloud Development Kit (AWS CDK).

Your schema registry configuration includes the registry endpoint URL, authentication method (AWS Identity and Access Management (IAM) for AWS Glue Schema Registry, or Basic Auth, SASL/SCRAM, or mTLS for Confluent registries), and validation settings. You specify which event attributes to validate and optionally define filtering rules using standard Lambda event filtering syntax.

For error handling, configure Lambda failure destinations where events that fail schema validation or deserialization are sent. This makes sure that problematic events don’t disappear silently but are routed to other services such as Amazon Simple Queue Service (Amazon SQS), Amazon Simple Notification Service (Amazon SNS), and Amazon S3 for debugging and analysis.

Seeing the new features in action

There are a number of Serverless Patterns that you can use to process Kafka streams using Lambda. This example uses the Java pattern.

Deploy a sample Amazon MSK cluster

To set up an Amazon MSK cluster, follow the instructions in the GitHub repo and create a new AWS CloudFormation stack using the MSKAndKafkaClientEC2.yaml template file. The stack creates the Amazon MSK cluster, along with a client Amazon EC2 instance, to manage the Kafka cluster. There are costs involved when running this infrastructure.

  1. Connect to the EC2 instance using EC2 Instance Connect.
  2. Check that the Kafka topic is created by checking the contents of the kafka_topic_creator_output.txt file.
    cat kafka_topic_creator_output.txt

  3. The file should contain the text: “Created topic MskIamJavaLambdaTopic.”

Deploy the Glue schema registry and consumer Lambda function

The EC2 instance contains the software needed to deploy the schema registry and Lambda function.

  1. Change directory to the pattern directory.
    cd serverless-patterns/msk-lambda-iam-java-sam
  2. Build the application using AWS SAM.
    sam build
  3. To deploy your application for the first time, run the following in the EC2 instance shell:
    sam deploy --capabilities CAPABILITY_IAM --no-confirm-changeset \
    	--no-disable-rollback --region $AWS_REGION --stack-name msk-lambda-schema-avro-java-sam --guided

  4. You can accept all the defaults by hitting Enter. You can browse to the AWS Glue schema registry console and view the ContactSchema definition:
    {
      "type": "record",
      "name": "Contact",
      "fields": [
        {"name": "firstname", "type": "string"},
        {"name": "lastname", "type": "string"},
        {"name": "company", "type": "string"},
        {"name": "street", "type": "string"},
        {"name": "city", "type": "string"},
        {"name": "county", "type": "string"},
        {"name": "state", "type": "string"},
        {"name": "zip", "type": "string"},
        {"name": "homePhone", "type": "string"},
        {"name": "cellPhone", "type": "string"},
        {"name": "email", "type": "string"},
        {"name": "website", "type": "string"}
      ]
    }
    

    The consumer Lambda function ESM is configured for Provisioned Mode.

  5. View the ESM configuration from the Lambda console for the Lambda function name prefixed with msk-lambda-schema-avro-ja-LambdaMSKConsumer.
  6. Choose the MSK Lambda trigger which opens the Triggers pane under Configuration.
    Figure 2: View Lambda ESM schema configuration
  7. The configuration specifies using the Event record format SOURCE so your function can use Kafka’s native open-source ConsumerRecords interface. Powertools then deserializes the payload.
  8. The schema validation attribute is VALUE.
  9. The ESM filter configuration only processes the records that match zip codes of 2000.
  10. In your function code, specify the open-source Kafka ConsumersRecords interface by including Powertools for Lambda as a dependency. ConsumerRecords provides metadata about Kafka records and allows you to get direct access to your Avro/Protobuf generated business objects without requiring any additional deserialization code.
package com.amazonaws.services.lambda.samples.events.msk;

import com.amazonaws.services.lambda.runtime.Context;
import com.amazonaws.services.lambda.runtime.RequestHandler;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;
import software.amazon.lambda.powertools.kafka.Deserialization;
import software.amazon.lambda.powertools.kafka.DeserializationType;
import software.amazon.lambda.powertools.logging.Logging;

public class AvroKafkaHandler implements RequestHandler<ConsumerRecords<String, Contact>, String> {
    private static final Logger LOGGER = LoggerFactory.getLogger(AvroKafkaHandler.class);

    @Override
    @Logging(logEvent = true)
    @Deserialization(type = DeserializationType.KAFKA_AVRO)
    public String handleRequest(ConsumerRecords<String, Contact> records, Context context) {
        LOGGER.info("=== AvroKafkaHandler called ===");
        LOGGER.info("Event object: {}", records);
        LOGGER.info("Number of records: {}", records.count());
        
        for (ConsumerRecord<String, Contact> record : records) {
            LOGGER.info("Processing record - Topic: {}, Partition: {}, Offset: {}", 
                       record.topic(), record.partition(), record.offset());
            LOGGER.info("Record key: {}", record.key());
            LOGGER.info("Record value: {}", record.value());
            
            if (record.value() != null) {
                Contact contact = record.value();
                LOGGER.info("Contact details - firstName: {}, zip: {}", 
                           contact.getFirstname(), contact.getZip());
            }
        }
        
        LOGGER.info("=== AvroKafkaHandler completed ===");
        return "OK";
    }
}
Produce and consumer records

To send messages to Kafka, there is a LambdaMSKProducerJava function.

  1. Invoke the function from the Lambda console or CLI within the EC2 instance.
    sam remote invoke LambdaMSKProducerJavaFunction --region $AWS_REGION \
    	--stack-name msk-lambda-schema-avro-java-sam

  2. You can view the Producer logs to see the 10 records produced.The consumer Lambda function processes the records.
  3. View the consumer Lambda function logs using the Amazon CloudWatch logs console or CLI within the EC2 instance.
    sam logs --name LambdaMSKConsumerJavaFunction \
    	--stack-name msk-lambda-schema-avro-java-sam --region $AWS_REGION

The Lambda function processes and logs only the records that match the filter FILTER. The Avro binary data is deserialized using Powertools for AWS Lambda. You should see the function logs showing each record processed with the decoded keys and values.


Figure 3: Lambda consumer logs showing Avro processing

Cleaning up

You can clean up the example Lambda function by running the sam delete command.

sam delete

If you created the Amazon MSK cluster and EC2 client instance, then navigate to the CloudFormation console, choose the stack, and choose Delete.

Performance and cost considerations

Schema validation and deserialization can add processing time before your function invocation. However, this overhead is typically minimal when compared to the benefits. ESM caching minimizes schema registry API calls. Using filtering allows you to reduce costs, depending on how effectively your filtering rules eliminate irrelevant events. This feature simplifies the operational overhead of managing schema registry integration code so teams can focus on business logic rather than infrastructure concerns.

Error handling and monitoring

If schema registries become temporarily unavailable, then cached schemas allow event processing to continue until the registry is available again. Authentication failures generate error messages with automatic retry logic. Schema evolution happens seamlessly as Lambda automatically detects and fetches new versions.

If events fail validation or deserialization, they are routed to your configured failure destinations. For Amazon SQS and Amazon SNS destinations, the service sends metadata about the failure. For Amazon S3 destinations, both metadata and the original serialized payload are included for detailed analysis.

You can use standard Lambda monitoring, with more CloudWatch metrics providing visibility into schema validation success rates, registry API usage, and filtering effectiveness.

Conclusion

AWS Lambda now supports Avro and Protobuf formats for Kafka event processing in Provisioned Mode for Kafka ESM. This enables schema validation, event filtering, and integration with both Amazon MSK, Confluent, and self-managed Kafka clusters. Whether you’re building new Kafka applications or migrating existing consumers to Lambda, this native schema registry integration streamlines processing pipelines.

For more information about the Lambda Kafka integration capabilities, go to the learning guide, Lambda ESM documentation. To learn about Lambda pricing, such as Provisioned Mode costs, visit the Lambda pricing page.

For more serverless learning resources, visit Serverless Land.

Amazon Q Developer Java Upgrades: A Deep Dive into the New Selective Transformation Feature

Post Syndicated from Venugopalan Vasudevan original https://aws.amazon.com/blogs/devops/amazon-q-developer-java-upgrades-a-deep-dive-into-new-selective-transformation-feature/

In the ever-evolving landscape of Java development, keeping applications up-to-date while minimizing risk has become increasingly challenging. Amazon Q Developer transformation capabilities now support customization of Java upgrades in Java upgrade transformation CLI (command line interface) with a new selective transformation feature. Selective transformation empowers development teams with greater control over their modernization journey. Instead of risky “big bang” upgrades, teams can now precisely target specific components and libraries for transformation while maintaining application stability. This surgical approach to modernization supports two key scenarios: individual developer-driven upgrades and orchestrated transformation campaigns managed by Center of Excellence (CoE) teams.

Using this feature, you can use natural language chat and/or an input file to tailor transformation plans and exercise greater control over Java upgrades. The following options are supported:

  1. Selection of steps from a transformation plan and breakdown of a transformation job for granular code reviews.
  2. Selection of first-party and third-party dependencies, along with their versions, that should be upgraded during JDK version upgrades.

In this blog post, we’ll explore how Java upgrade transformation CLI’s selective transformation capabilities help development teams efficiently manage Java version upgrades, reduce technical debt, and modernize their applications with minimal disruption. We’ll demonstrate practical examples of various scenarios of upgrading First-Party and Third-Party dependencies and also using an input file or natural language to guide the transformation process.

About Selective Transformation

With introduction of this selective transformation feature, the java upgrades will be completed in two phases:

  • Job 1 – Minimum JDK Upgrade: The first qct transform command will focus on performing the minimum changes necessary to upgrade the project JDK version.
  • Job 2 – Dependency Upgrade: To upgrade the project’s dependencies, run the qct transform command again on the newly upgraded Java 17/21 project. This second job will then handle only the dependency upgrades.

Dependency Upgrade Input file

Dependency upgrade file is an optional input to the qct transform command where the user can specify the versions of first-party and third-party dependencies that needs to be upgraded.

  • Structure the dependency_upgrade.yml (or any other name you prefer) in the following format:
name: dependency-upgrade
description: "Custom dependency version management for Java migration from JDK 8/11/17 to JDK 17/21"

dependencyManagement:
  dependencies:
    - identifier: "groupId:artifactId" # Required
      targetVersion: "2.1.0" # Required
      versionProperty: "library1.version"  # Optional
      originType: "FIRST_PARTY" # or "THIRD_PARTY"  # Required
    - identifier: "com.example:library2" # Required
      targetVersion: "3.0.0" # Required
      originType: "THIRD_PARTY" # Required
  plugins:
    - identifier: "groupId:artifactId"
      targetVersion: "1.2.0"
      originType: "THIRD_PARTY"
      versionProperty: "plugin.version"  # Optional
  • For each dependency or plugin you want to upgrade:
    • Under dependencies or plugins, add a new entry.
    • Specify the identifier
    • Set the targetVersion to the desired version.
    • Specify originType as “FIRST_PARTY” or “THIRD_PARTY”.
    • Optionally, include versionProperty if the version is managed by a property.
  • When running the migration command, include the --dependency_upgrade_file flag followed by the path to your YML file:
qct transform \
--source_folder <path-to-folder>\
--target_version <17 or 21> \
--dependency_upgrade_file <path-to-dependency_upgrade.yml>\
--no-interactive

Interactive and No-Interactive Mode

You can run the selective transformation upgrades in either no-interactive or interactive mode

For no-interactive mode , you need to specify --no-interactive flag , where the transformation will proceed with planning and execution without waiting for any user input in an interactive fashion.

Interactive mode is a new “chat” option in the CLI where once the plan is generated, user can type feedback in natural language and specify to skip steps or specify particular versions of dependencies to be upgraded to guide the transformation process.

Interactive Mode Usage Examples:

  1. Ask to change dependencies “Can you upgrade junit to version 4.15 instead of 4.12?”
  2. Ask to remove steps “Can you skip plan step 3”
  3. Ask to remove certain dependencies “I don’t want my springboot to be upgraded at this time”
  4. Invalid Input (should be thrown away and will prompt again) “What is the capital of France?”
  5. Start message: “The plan looks good” or “Go ahead with transformation” or “Looks Good”
  6. Add first party dependency “Could you help me also upgrade the dependency XXX:XXXX”

Example Transformation

Pre-requisites:

  1. Refer to the link for general instructions on installation of transformation CLI : https://docs.aws.amazon.com/amazonq/latest/qdeveloper-ug/run-CLI-transformations.html
  2. Clone the repo from https://github.com/aws-samples/aws-appconfig-java-sample

Mode 1 : Interactive : Upgrade Java v1.8 to Java v21

We will use interactive mode to transform this 1.8 project to 21 along with a 1P dependency upgrade to 21 as well.

Refer to example 1p dependency upgrade file

Initiate the transformation using command below:

qct transform \
--source_folder /home/ec2-user/qct/aws-appconfig-java-sample\
--target_version 21 \
--dependency_upgrade_file /home/ec2-user/qct/dependency_upgrade_1p.yml\
--no-interactive

Amazon Q performs transformations based on your project's requests, descriptions, and content. To maintain security, avoid including external, unvetted artifacts in your project repository and always validate transformed code for both functionality and security. Do you want to proceed? [Y/N]: Y

Choose Y to proceed with the transformation.

Once the Job is accepted, during the planning phase, agent will display the plan based on the input dependency upgrade file provided to include 1P upgrade as part of the plan. (if no dependency upgrade file is provided, user can still provide feedback on the plan). Here we say Looks good, proceed with the transformation.

For this transformation, I'll make the necessary changes to upgrade your Java 8 application to Java 21.

Here is the transformation plan that includes your first party dependencies:
Step 0: Minimal migration to Java 21
Step 1:

            * Update/Add 1P dependency com.amazonaws.samples:movie-service-utils to version 0.3.0

If you would like to modify the plan, you can ask me to:

    * Add first party dependencies and versions to upgrade to
    * Change the target versions of the first party dependencies

You can enter plan feedback, or let me know if you want to start the transformation now: Looks good, proceed with the transformation

If is there is any user feedback , the agent will display the revised plan for the user to accept, if not it will proceed with the transformation. Upon completion, the agent will display the status, provide the location of the summary file containing the changes, and confirm the creation of a new branch with these changes. You can run git diff mainlineto review the changes and accept.

Fig 1 part of pom.xml changes after transformation from 8 to 21

Fig 1: part of pom.xml changes after transformation from 8 to 21

The transformation agent was able to upgrade Java 8 to Java 21 version along with dependencies minimally required for v21 and also the 1P dependency specified in the upgrade file.

Mode 1 : Interactive : Upgrade dependencies

Initiate the transformation using the same command as seen below:

qct transform \
--source_folder /home/ec2-user/qct/aws-appconfig-java-sample\
--target_version 21 \

Once the Job is accepted, during the planning phase, the transformation agent will display the transformation plan and ask the user input for any feedback to upgrade 3P dependencies to a specified version if needed.

For this transformation, I'll upgrade libraries and other dependencies to modernize your Java 21 application.

Here is the transformation plan:
Step 1:

        * Update javax.validation:javax.validation-api

Step 2:

        * Update org.mockito:*
        * Update org.springframework.boot:spring-boot-starter-parent to version 3.3.4
        * Update org.springframework.boot:spring-boot-starter-test to version 3.3.4

Step 3:

        * Update org.apache.logging.log4j:*

Step 4:

        * Update org.springframework.boot:spring-boot-maven-plugin to version 3.3.4
        * Update org.springframework.boot:spring-boot-starter-web to version 3.3.4

Step 5:

        * Update org.apache.logging.log4j:log4j-api to version 2.24.0
        * Update org.apache.logging.log4j:log4j-core to version 2.24.0

Step 6:

        * Update org.json:json to version 20240303

Step 7:

        * Update software.amazon.awssdk:appconfig to version 2.28.6
        * Update software.amazon.awssdk:bom to version 2.28.6

If you would like to modify the plan, you can ask me to:

* Only upgrade certain libraries
* Change the target version of a library
* Only perform certain steps in the plan

You can enter plan feedback, or let me know if you want to start the transformation now:

For this example,

Let’s say "Skip Step 6, upgrade org.springframework.boot:spring-boot related libraries and plugin to 3.4.5, upgrade software.amazon.awssdk:appconfig to version 2.31.40 and Update software.amazon.awssdk:bom to version to 2.31.40"

Transformation agent will display the revised plan for the user to accept, and ask confirmation to proceed with the transformation.

Here is the updated transformation plan:
Step 1:

        * Update javax.validation:javax.validation-api

Step 2:

        * Update org.mockito:*
        * Update org.springframework.boot:spring-boot-starter-parent to version 3.4.5
        * Update org.springframework.boot:spring-boot-starter-test to version 3.4.5

Step 3:

        * Update org.apache.logging.log4j:*

Step 4:

        * Update org.springframework.boot:spring-boot-maven-plugin to version 3.4.5
        * Update org.springframework.boot:spring-boot-starter-web to version 3.4.5

Step 5:

        * Update org.apache.logging.log4j:log4j-api to version 2.24.0
        * Update org.apache.logging.log4j:log4j-core to version 2.24.0

Step 6:

        * Update software.amazon.awssdk:appconfig to version 2.31.40
        * Update software.amazon.awssdk:bom to version 2.31.40

If you would like to modify the plan, you can ask me to:

* Only upgrade certain libraries
* Change the target version of a library
* Only perform certain steps in the plan

You can modify the plan 4 more time(s) before I start the transformation.

You can enter plan feedback, or let me know if you want to start the transformation now: Looks good

Fig 2 part of pom.xml changes after dependency upgradesFig 2: part of pom.xml changes after dependency upgrades

The transformation agent was able to upgrade 3P dependencies specified via the interactive mode during the planning stage.

Mode 2 : No-Interactive : Java v1.8 to Java v21

We will use no-interactive mode to transform this 1.8 project to 21 along with 1P version upgrades with dependency upgrade

The transformation agent will not wait for any user inputs and directly upgrade the project from Java 1.8 to 21 with along with dependencies minimally required for this upgrade.

Refer to example 1p dependency upgrade file

Initiate the transformation using command below:

qct transform \
--source_folder /home/ec2-user/qct/aws-appconfig-java-sample \
--target_version 21 \
--dependency_upgrade_file /home/ec2-user/qct/dependency_upgrade_1p.yml \
--no-interactive

Fig 3 part of pom.xml changes showing 1P upgrades

Fig 3: part of pom.xml changes showing 1P upgrades

The transformation agent was able to upgrade the Java version along with 1P dependency specified.

Mode 2 : No-Interactive : Upgrade dependencies

We will use no-interactive mode to upgrade the 3P dependencies

Refer to example 3p dependency upgrade file

Initiate the command below:

qct transform \
--source_folder /home/ec2-user/qct/aws-appconfig-java-sample \
--target_version 21 \
--dependency_upgrade_file /home/ec2-user/qct/dependency_upgrade_3p.yml \
--no-interactive

Fig 4 of pom.xml changes showing 3P upgrades

Fig 4: part of pom.xml changes showing 3P upgrades

The transformation agent was able to upgrade 3P dependencies along with the versions provided by the user via the dependency upgrade file.

Conclusion

The introduction of selective transformation in Java upgrade transformation CLI marks a significant evolution in how teams can approach Java modernization. By offering granular control over upgrade paths, supporting natural language interactions, and enabling targeted dependency management, this feature transforms what was once a daunting technical challenge into a manageable, incremental process. As a next step, start by identifying your most critical components that need upgrading, and leverage the selective transformation feature to create a tailored upgrade strategy. Visit the Amazon Q Developer transformation CLI documentation to learn more about implementing these capabilities in your development workflow, and join the growing community of developers who are revolutionizing their approach to Java modernization. The future of efficient, risk-managed Java upgrades is here – it’s time to embrace it.

About the authors

saptob Saptarshi Banerjee serves as a Senior Solutions Architect at AWS, collaborating closely with AWS Partners to design and architect mission-critical solutions. With a specialization in generative AI, AI/ML, serverless architecture, Next-Gen Developer Experience tools and cloud-based solutions, Saptarshi is dedicated to enhancing performance, innovation, scalability, and cost-efficiency for AWS Partners within the cloud ecosystem.
sureshnt Sureshkumar Natarajan is a Senior Technical Account Manager at AWS based in Denver, CO. He specializes in supporting Greenfield and SMB customers on the AWS platform. His expertise includes AWS Generative AI Services, AWS ECS/EKS Container solutions, and helping Enterprise Support customers to build well-architected solutions in AWS
vasudeve Venugopalan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation.

Announcing General Availability of GitLab Duo with Amazon Q

Post Syndicated from Ryan Bachman original https://aws.amazon.com/blogs/devops/announcing-general-availability-of-gitlab-duo-with-amazon-q/

Announcing General Availability of GitLab Duo with Amazon Q

Today, we’re excited to announce the general availability of GitLab Duo with Amazon Q. This new offering is an integrated product, bringing together GitLab’s DevSecOps platform with Amazon Q’s generative AI capabilities. Gitlab Duo with Amazon Q embeds Amazon Q agent capabilities directly in GitLab’s DevSecOps platform to accelerate complex, multi-step tasks across the entire software development lifecycle.

In today’s fast-paced software development environment, developers are constantly looking for ways to improve productivity while maintaining best practices for code quality, security, and deployment. The integration of GitLab Duo with Amazon Q addresses these needs by combining GitLab’s comprehensive DevSecOps platform with Amazon Q’s intelligent coding assistance.

This integration enables developers to leverage AI throughout their entire workflow—from idea conception to deployment—all within the familiar GitLab environment they already use. For new and existing Amazon Q Developer users, this integration also leverages the same Q Developer agents available in the IDE, providing a consistent experience across different interfaces.

Key Benefits and Features

The GitLab Duo with Amazon Q integration delivers significant value to development teams by creating a more efficient, secure, and collaborative workflow.

This integration eliminates the need to switch between different tools and environments, as developers can access powerful AI assistance directly within GitLab. GitLab helps automate building, testing, packaging, and deployment of secure code, streamlining the entire development lifecycle. What makes this particularly powerful is how the AI agents utilize the context throughout a GitLab project to keep the SLDC “loop” going. So whether you are troubleshooting a failed pipeline, investigating a vulnerability, or writing a new feature, Amazon Q agents can leverage the appropriate context to assist you with the task at hand.

Security and compliance are foundational elements of this integration. End-to-end security controls are built directly into the platform. The Amazon Q agents come with appropriate guardrails to help customers meet compliance without affecting development velocity, all while leveraging AWS’s cloud infrastructure to scale your AI-enhanced development workflows with confidence. You can ask Amazon Q agents to help remediate a finding in the project’s vulnerability reports or help troubleshoot a failed pipeline.

Throughout your development workflow, you’ll find collaborative AI agents ready to assist with various tasks. Whether you need to upgrade Java code from version 8 or 11 to 17, get AI-powered code review suggestions, automatically generate comprehensive test cases, or transform ideas into complete merge requests—Amazon Q is there to help at every step. These intelligent agents work alongside your team, enhancing productivity.

Use Cases and Examples

To demonstrate how GitLab and Amazon Q complement each other to accelerate development productivity and help organizations with application security, I’ll be using a Java application enjoyed by puzzle enthusiasts.

A Video of playing Q Words

Idea to Merge Request

Whether you are looking to scale your developer teams or streamline the processes between feature requests and production, GitLab Duo with Amazon Q is now integrated into GitLab’s platform, so you can begin development simply by assigning a GitLab issue to Amazon Q Developer agents.

I start by creating a task in my GitLab project. I want to create a new feature to support multiple languages in the Q words game.

Creating a new issue for the Q Dev agent

From here I assign the task directly to the Amazon Q agent by using GitLab’s quick action /q dev in the issue’s comment section.

Invoking the Q Dev Agent with a quick action

The agent will automatically open up a merge request for me to review with suggested code changes. Here you can see changes the agent made across 11 files, accounting for front-end, API, and styling changes. In the past I would have opened my IDE, cloned the project, and coded these changes myself. Using GitLab Duo with Amazon Q, I just review and test the new code before I am ready to deploy.

The merge request created by the Q Dev Agent

Code Reviews

Code reviews play a critical function during the development life-cycle. They act as a quality gate to help maintain high quality security and coding standards. While important, code reviews add latency to software delivery, especially when reviewers are not available or when changes are complex.

The Amazon Q agent for Code Reviews in GitLab helps teams move faster through their code review. Using the quick action /q review in a merge request comment field sends the merge request to Amazon Q, where it will identify security and quality risks associated with code changes in the merge request.

I start by opening an open merge request. In this example, another developer had the task to add authentication to the Q words application.

I then invoke the agent with the /q review quick action.

Invoking the Q review agent

The review is returned as inline code suggestions to the merge request. Here you can see an example of a finding from the review agent. Comments include a description of the findings as well as guidance and links to help improve the code.

Amazon Q Review adds comments to the merge request

I next use the Gitlab Duo with Amazon Q chat agent in the web interface to ask for a summary of the change and ask it to highlight any critical issues. GitLab Duo chat allows me to ask questions about the current resource in the URL. In this example it is the merge request, but it could also be a GitLab issue I want to explain or a summary of a code file in a repository.

Chatting with GitLab Dou with Amazon Q

Test Generation

Next, I ask GitLab Duo with Amazon Q to generate tests using the /q test quick action. Adding this action to the comment field will generate recommended tests when the MR lacks sufficient tests.

A test recommened by the Q test agent

The summary I receive from GitLab Duo with Amazon Q helps me understand the scope of the changes and focuses my attention to the more important aspects of the change. Along with the tests that Q Developer agents recommended, I am able to approve the merge request in less time.

Java Transformation

Upgrading Java applications from older versions to Java 17 can be time-consuming and error-prone. With GitLab Duo and Amazon Q, I can leverage the transform agent to help me automate the migration from the current Java 8 code to Java 17 along with upgrading the project’s dependencies. I start by creating a new issue in my GitLab project that indicates the Java upgrade.

Creating a new issue for the Q Transform agent

To begin the upgrade, I use the GitLab Q quick action /q transform to begin the upgrade process. The Amazon Q transformation agent asks me to update the gitlab-ci.yaml file to continue the process.

Instructions on how to update your .gitlab-ci.yaml file

I can follow the agent’s progress by watching for updates in the Issue’s details. GitLab Duo with Amazon Q will also add a transformation plan to the issue so I can understand what types of changes will be involved to complete the upgrade.

The Amazon Q Agent will provide a transformation plan before it begins

When the transform is complete, a new merge request is opened for me to review. As you can see, my pom.xml file was updated to compile on Java 17 as well as additional changes to ensure the project compiles. It also includes a report detailing next steps to consider before merging and deploying the updated Java code.

A completed summary from the Q transform agent

Conclusion

In this post, I demonstrated how GitLab Duo with Amazon Q can help scale and improve application development. Using GitLab Duo with Amazon Q, I was able to quickly add additional features, review code changes, and upgrade my application to Java 17 all within GitLab’s collaborative interface. I now have a secure and modern java app that I can use to practice my Español.

The general availability of GitLab Duo with Amazon Q marks a significant milestone in AI-assisted software development. By combining GitLab’s comprehensive DevSecOps platform with Amazon Q ‘s generative AI capabilities, this integration empowers development teams to work more efficiently while maintaining high standards of security and compliance.

Organizations can now leverage this powerful integration to accelerate their software development lifecycle, reduce manual effort, and ship more secure code faster. The seamless developer experience, enterprise-grade security, and collaborative AI agents throughout the workflow make this integration a valuable addition to any development team’s toolkit. We’re excited to see how customers leverage this integration to transform their development processes and achieve new levels of productivity and innovation.

Learn More

About the Author:
Ryan Bachman profile image

Ryan Bachman

Ryan Bachman is a Sr. Specialist Solutions Architect with Amazon Web Services (AWS) Next Generation Developer Experience Team. Ryan is passionate about helping customers adopt process and services that increase their efficiency developing applications for the cloud. He has over 20 years professional experience as a technologist, including roles in development, network architecture, and technical product management.

Accelerate large-scale modernization of .NET, mainframe, and VMware workloads using Amazon Q Developer

Post Syndicated from Krishna Parab original https://aws.amazon.com/blogs/devops/accelerate-large-scale-modernization-of-net-mainframe-and-vmware-workloads-using-amazon-q-developer/

Software runs the world – not just the new software applications built in modern languages and deployed on the most optimized cloud infrastructure, but also legacy software built over years and barely understood by the teams that inherit them. These legacy applications may have snowballed into monolithic blocks or may be fragmented across siloed on-premises infrastructure. The significant maintenance, security, and compliance challenges caused can create lasting implications for business performance and competitiveness. Therefore, transformation of legacy applications using modern languages, new frameworks, and cloud services has become an organizational imperative.

Application modernization challenges

Modernization of software applications is a long and painful journey – requiring large teams of developers, domain experts, and consultants who first need to understand the application landscape, devise strategic modernization plans, and then tactically implement the plans in phases, typically over a span of many years. This process is linear, slow, and complex. Traditional labor-intensive modernization approaches incur significant costs and take years to leverage new cloud technologies and innovations for business-critical applications.

Generative AI can help with intelligent automation, domain expertise, and scalability to transform modernization journeys.

Introducing Amazon Q Developer transformation capabilities

Q Developer transformation capabilities powered by LLMs and domain-expert agents support human-agent interaction via an IDE experience for individual developers and a web experience for multifunctional teams.

Amazon Q Developer transformation capabilities

Amazon Q Developer, the most capable generative AI–powered assistant for software development, is now the first generative AI-powered assistant for large-scale modernization and migration of .NET, mainframe, and VMware workloads. This extends Q Developer’s transformation capabilities for Java upgrades launched in April 2024 to new types of workloads. Q Developer combines both foundational models and specialized tools based on AI and automated reasoning via autonomous agents that tackle workload-specific modernization steps spanning analysis, planning, and implementation.

Multifunctional teams, including consultants, IT experts, workload domain experts, and developers, can use a unified web experience to offload transformation tasks to Amazon Q Developer agents and transform hundreds of workloads at a time. The agents can port .NET Framework to cross-platform Linux-ready .NET, modernize COBOL applications on mainframes to Java applications on AWS, or virtualized workloads on VMware to scalable workloads on EC2. The modernization teams engage with Q Developer using natural language and share transformation objectives, code repositories, and context. Q Developer agents analyze artifacts like code segments, dependencies, and integrations, applying expertise from prior modernizations. They propose customized plans tailored to codebases, resource utilization, and objectives. The teams can then review, adjust, and approve the plans with iterative engagement with the agents. After the plans are approved, the agents implement the transformation keeping the modernization teams updated on milestones completed and blockers needing human guidance. The transformation journey is an interactive process between the modernization team and Q Developer, with modernization team maintaining control and visibility over the transformation.

Human team members interact with Q Developer generative AI agents using natural language chat.

Natural language chat with Q Developer AI agents

Faster, scalable, and better modernization

Amazon Q Developer enhances transformation in three primary ways – acceleration, scalability, and quality.

Amazon Q Developer automates and accelerates complex, multi-step processes. Agents conduct assessment and discovery of legacy artifacts to build documentation and dependency maps that improve the understanding of source assets. Most large-scale modernization projects are done in waves that need to be carefully planned. The agents develop modernization wave plans based on source dependencies, stated project goals, and teams can review and approve the plans. Thereafter, the goal-seeking autonomous agents handle implementation complexities to execute the plans. Customers using Amazon Q Developer can modernize Windows .NET applications to Linux up to four times faster than traditional methods and help customers realize up to 40% savings in licensing costs. Migration Planning for the sequence to transform monolith z/OS COBOL application code that takes months to accomplish with human subject matter experts, Amazon Q Developer generates in minutes. Q Developer agents convert on-premises VMware network configurations into modern AWS equivalents in hours vs. the weeks required with traditional manual approaches. The shorter time spent on manual modernization means more freedom for your team to focus on innovation.

Modernization has traditionally been a linear journey with multiple steps and dependencies on cross-functional teams with limited mechanisms for collaboration. This limits teams’ ability to tackle large-scale projects. Amazon Q Developer addresses the challenges by task parallelization and web-based collaboration. Multiple generative AI agents work simultaneously on tasks. Large monolithic applications can be decomposed along business functions like engineering, marketing, sales applications, and transformed in parallel. A unified web-based experience for large-scale transformation means multi-functional team members can collaborate with the autonomous agents, and review and approve key decisions in one place, enabling teams to execute larger and more complex projects in a given time.

Finally, the quality of transformation manifested in functional equivalence, security, and resilience of modernized applications determines the business outcomes like project ROI and operational performance. To ensure transformation quality, you need expertise in languages and frameworks like COBOL, Java, .NET; specialized steps like code base analysis, monolith decomposition, code refactoring, network translation; and domains like mainframe, virtualization, and cloud. You may not have the requisite expertise in your team. That is where Amazon Q Developer can help. Q Developer agents are trained with specific domain expertise to identify code dependencies and frameworks, replace deprecated code, upgrade to new language frameworks, incorporate security best practices, and validate upgraded workloads using workload-tailored plans. Your team can examine the agents’ recommendations, make informed decisions, and guide the modernization journey towards better outcomes like enhanced security, compliance, and performance.

Q Developer supports modernization of .NET Framework applications to cross-platform .NET applications, mainframe-based COBOL applications to Java applications on AWS, on-premises VMware workloads to workloads on EC2, and Java v8/11/17 to Java17/21.

Workloads supported by Amazon Q Developer transformation capabilities

Next steps

Amazon Q Developer transformation capabilities are now available in preview. To learn more, please visit Q Developer web page featuring short demo videos and documentation that can get you started. Read the AWS News blogs that walk you through the unified web experience and IDE experience. Dive deeper into the transformation of specific workloads by reading the workload-specific blogs related to transformation of .NET, mainframe, and VMware workloads.

About the author:

Elio Damaggio

Krishna Parab

Krishna B. Parab leads product marketing for Amazon Q Developer transformation capabilities. He has over 13 years of experience in product marketing and prior experience in engineering and product management. He has led marketing for Cisco Cloud, ServiceNow service management SaaS, Arm Pelion IoT platform, Automation Anywhere RPA platform, and AWS Mainframe Modernization service. Krishna’s educational background includes BTech, MS, and MBA degrees from IIT Bombay, UT Austin, and University of Michigan, respectively.

Elio Damaggio

Elio Damaggio

Elio Damaggio is the product lead for the transformation capabilities of Amazon Q Developer. With more than 15 years in tech, 11 patents, and a PhD in Computer Science, he is now looking for exciting ways to empower developers through AI.

Announcing inline chat in Eclipse with Amazon Q Developer

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/announcing-inline-chat-in-eclipse-with-amazon-q-developer/

Earlier today Amazon Q Developer launched inline chat in the Eclipse IDE (in preview). In this post, I’ll walk you through how I’ve been using this powerful new capability to streamline my Java development workflow, from refactoring existing code to optimizing performance-critical methods. Whether you’re a seasoned Eclipse veteran or just getting started, you’ll see how Amazon Q Developer’s advanced AI-driven tools can supercharge your productivity across the entire software development lifecycle.

Background

As a long-time Java developer, I was thrilled when Amazon Q Developer was integrated in Eclipse last year. I’ve been using Amazon Q Developer for a while now, and it has completely transformed my development workflow. When Amazon Q Developer first launched its inline suggestions feature back in 2022, I was blown away by how much it could accelerate my coding tasks. But the addition of a full chat interface in 2023 took things to the next level. Then in 2024 the new inline chat capability allowed me to edit and refactor my code in place. However, inline chat was not available in Eclipse, until today!

The chat interfacein Amazon Q Developer is where I turn when I’m not quite sure how to accomplish a particular task. I love being able to explain the problem I’m trying to solve, or the concept I’m trying to understand, and getting detailed, contextual responses that help point me in the right direction. The AI-generated code snippets and explanations are invaluable when I’m learning something new or tackling a complex challenge. However, when I know how to accomplish a task, I don’t need the explanation I just want the code.

On the other hand, when I’m workingon a well-understood task, I much prefer to use Amazon Q Developer’s inline suggestions. The way it analyzes my existing code and comments to provide relevant, customized completions is just incredible. It lets me work at faster, creating new functionality without having to constantly switch context or hunt for the right syntax. However, while inline suggestions are great for generating new code, I cannot use it to edit existing code.

Now, with the new inline chat feature in Eclipse (in preview), I can easily edit my code in place using Amazon Q Developer. Instead of having to copy/paste code from a separate chat window, I can describe the changes I want to make right in the editor, and Amazon Q Developer will seamlessly integrate the suggested updates into my code base as a diff. It’s great for for refactoring, bug fixing, and maintaining well-documented, easily-readable code. Let’s look at a couple of examples to see how inline chat works in Eclipse.

Refactoring

Imagine that I am the newest member of a development team, and I was tasked with adding unit tests to the OrderProcessor class. However, as I dug into the code base, I realized that the OrderProcessor was tightly coupled to the OrderRepository implementation. Notice the instantiation of the OrderRepository on line 2 in the following image. This made it difficult to write unit tests, as I couldn’t easily swap in a mock repository. I knew I needed to refactor the code to use dependency injection, but the thought of making all of those changes manually was daunting.

Java code showing complete OrderProcessor class implementation with order processing logic, including order validation and persistence methods using IOrderRepository interface.

Fortunately, with Amazon Q Developer’s inline chat in my Eclipse IDE, I didn’t have to tackle this refactor alone. I selected the OrderProcessor class, invoked the inline chat using the keyboard shortcut (CMD + SHIFT + I for macOS, and CTRL + SHIFT + I for Windows). Then I described the change I want: “Refactor this class to use dependency injection so I can mock the OrderRepository in unit tests.” Note that I could have also asked Amazon Q Developer to leverage a specific DI framework, like Hibernate. However, I am going to keep this simple for the blog post.

Java code displaying OrderProcessor class with a prompt to refactor using dependency injection. Shows current implementation with direct instantiation of OrderRepository and validation methods.

Amazon Q Developer quickly analyzed the code and presented me with a suggested change shown in the following image. The change is presented as a diff so I can see what Amazon Q Developer is removing (in red) and adding (in green). After reviewing the changes, I was pleased to see that Amazon Q Developer had introduced a constructor that took an IOrderRepository interface, allowing me to pass in either the concrete implementation or a test double. This would make it a breeze to write comprehensive unit tests for the OrderProcessor. With a quick click to accept the changes, Amazon Q Developer updated my code, saving me valuable time and ensuring the new feature would be built on a solid, testable foundation.

Java code showing OrderProcessor class with dependency injection prompt. Contains processOrder method that validates and saves orders using an IOrderRepository interface. The code includes validation logic and database operations.

In this example, I selected the entire class. However, I can also ask Q Developer to work on a specific portion of the code.

Optimization

While working on the Order class, I noticed that the containsItem method seemed to be running slowly, especially on orders with a large number of line items. I decided to profile the code and sure enough, that method was a hot spot, consuming a disproportionate amount of CPU cycles. I selected the containsItem method, brought up the inline chat, and asked Amazon Q Developer: “This code is running slow, please optimize it.”

Java code displaying Order class with a popup message suggesting optimization. Shows class fields for id, customer, and items, with a containsItem method implementation using a for loop that could be optimized.

Amazon Q Developer quickly analyzed the existing code, which was using a simple for loop to iterate through the list of items, and provided an improved implementation. As shown in the diff, Amazon Q Developer suggested replacing the for loop with a more efficient stream-based approach, using the anyMatch method to determine if the item is present in the order. This change has improved performance, especially for orders with a large number of line items. I reviewed the changes and accepted Amazon Q Developer’s suggestions.

Java code showing Order class with highlighted section suggesting replacement of traditional for loop with Java 8 Stream API. Contains an implementation of containsItem method with both the original loop and a commented stream-based solution.

Amazon Q Developer’s optimization not only improved the performance of the containsItem method, but also made the code more readable and maintainable going forward.

Conclusion

The integration of Amazon Q Developer into the Eclipse IDE (in-preview) has improved my Java development workflow. Whether I’m learning a new concept, generating boilerplate code, or optimizing a performance bottleneck, Amazon Q Developer’s suite of AI-powered tools has become an indispensable part of my development process. The addition of inline chat, in particular, has streamlined my ability to directly interact with the assistant, seamlessly updating my code base without breaking my concentration. If you’re an Eclipse user looking to supercharge your productivity, I highly recommend installing the Amazon Q Developer plugin today.

Using Amazon Q Developer CLI for custom Java application transformations

Post Syndicated from Dinesh Prabakaran original https://aws.amazon.com/blogs/devops/using-amazon-q-developer-cli-for-custom-java-application-transformations/

In today’s rapidly evolving software landscape, maintaining and modernizing Java applications is a critical challenge for many organizations. As new Java versions are released and best practices evolve, the need for efficient code transformation becomes increasingly important. Amazon Q Developer transformation for Java using the Command Line Interface (CLI) presents a powerful alternative to integrated development environments (IDEs), offering unique advantages in scenarios requiring batch processing, CI/CD integration, headless environments, and custom automation workflows. By leveraging the CLI, development teams can perform consistent, scalable, and easily reproducible transformations across extensive codebases.

One key difference between CLI and IDE-based transformations lies in the standardization and customization capabilities. With CLI transformations, teams can define and enforce standardized transformation rules across the entire organization, ensuring consistency in code modernization efforts. This standardization is particularly valuable for large teams or distributed development environments. Additionally, the CLI approach allows for deeper customization of transformation rules, enabling teams to tailor the modernization process to their specific needs and coding standards. Whether updating deprecated APIs, migrating to newer Java versions, or enforcing coding standards, Amazon Q Developer’s CLI transformations provide a flexible and powerful solution.

This blog will explore how to use Amazon Q Developer’s CLI capabilities to create custom transformations for upgrading Java applications. We’ll dive into the process of defining transformation rules, executing them across your codebase, and demonstrate how to customize these transformations to meet specific requirements. By the end of this blog, you’ll have a clear understanding of how to leverage Amazon Q Developer’s CLI for Java transformations, enabling you to modernize your applications more efficiently and with greater control. You’ll be equipped to standardize your transformation processes across teams and projects while also customizing them to fit your unique requirements.

Pre-requisites

Before you begin a transformation, see the prerequisites for transformation on the command line with Amazon Q Developer.

Note: The Amazon Q Developer command line tool for transformation (qct cli) is distinct from the Amazon Q Developer CLI – while qct cli is specifically designed for code transformations, the Amazon Q Developer CLI provides features such as autocompletion, Amazon Q chat, inline ZShell completion, etc.

These pre-requisites ensure that you have all the necessary tools and permissions to use Amazon Q Developer’s CLI capabilities for custom transformations on your Java applications.

About the Application

This sample project will be used to demonstrate the Amazon Q Developer CLI code transformation feature in action. It’s a Java 1.8 based microservice application that displays a free list of movies for the month using configuration stored in AWS AppConfig service. Originally open sourced in 2020, it intentionally uses legacy versions of libraries (Spring Boot 2.x, Log4j 2.13.x, Mockito 1.x, Javax and Junit 4) to showcase the upgrade process. The application includes a dependency on another module built in both Java 1.8 and 17, specifically to demonstrate how post transformation steps can be used to modernize your application’s internal dependencies. You can download this sample project to experiment with the CLI upgrade feature in your own environment.

Overview

You will use Amazon Q Developer command line tool for transformation to perform custom transformations on a Java application. This will involve:

  1. Configure Amazon Q command line tool for transformation.
  2. Use pre-transformation template to identify unused imports and variables and remove them before transformation.
  3. After pre-transformation, upgrade the application to Java 17 to leverage the latest features.
  4. Use post transformation template to
    • Modify the POM file to point internal dependencies to the latest Java 17 or 21 (1p) version.
    • Modify your code to replace deprecated methods from internal dependencies.
    • Identify System.out.println statements and replace them with a proper logger framework.

Walkthrough

Setting up the transformation environment

First, ensure you have the Amazon Q command line tool for transformation installed. You can verify this by running:

which qct

Figure 1: Output of 'which qct' command showing the installation path of Amazon Q Developer CLI
Figure 1: which qct

If it’s not installed, follow the installation instructions in the Amazon Q Developer documentation.

Configuring Amazon Q command line tool and authenticate

Configure the Amazon Q command line tool for transformation by running the qct configure command:

qct configure

This command will:

  1. Prompt you to specify the JDK path for Java 8, 11, 17 and 21. You only need to specify the path to the JDK of the Java version you are upgrading.
  2. Two options are available for authentication
    • Option 1 authenticates with IAM credentials stored in your AWS CLI profile. Refer Figure 2.
    • Figure 2: Screenshot showing the Amazon Q Developer CLI authentication prompt using IAM credentials, displaying AWS profile selection options
    • Figure 2: qct configure – Authenticate with IAM
      • Provide the AWS CLI profile to use for the IAM authentication. You can specify a specific profile name or press enter to use the default profile.
      • Provide a file path that will point to a CSV file which will be used to add tags for your transformation (optional). The CSV must have two columns, with headers titled key and value, where tag key-value pairs are listed.
    • Option 2 authenticates with IDC (IAM Identity Center). Refer Figure 3.
    • Figure 3: Screenshot of Amazon Q Developer CLI configuration screen showing IAM Identity Center (IDC) authentication options and prompts
    • Figure 3: qct configure – Authenticate with IDC
      • Prompt you to provide the Start URL to authenticate to Amazon Q Developer Pro. The Start URL can be obtained from the console in the Q Developer > Settings.
      • Provide the AWS Region
  3. If you’re upgrading your code’s Java version, you have the option to receive your code suggestions from Amazon Q in one commit or multiple commits. Amazon Q will split the upgraded code into multiple commits by default. If you want all your code changes to appear in one commit, enter the letter ‘O’ for one commit when prompted.

For more information on how Amazon Q splits up the code changes, see Reviewing the transformation summary and accepting changes.

Customizing transformations

You can customize transformations by providing custom logic in the form of ast-grep rules that Amazon Q uses to make changes to your code.

To start with customization, create an Orchestrator file where you provide the paths to the custom transformation files. The Orchestrator file is a YAML file containing paths to custom pre-transformation and post-transformation files, which contain ast-grep rules that will run before and after transformation.

Here’s an example:

orchestrator_qct_cli.yaml

name: orchestrator_qct_cli
description: My collection of custom transformations to run before and after a transformation.

pre_qct_actions:
  ast-grep:
    rules:
      - custom-transformation-pre-qct.yaml

post_qct_actions:
  ast-grep:
    rules:
      - custom-transformation-post-qct.yaml

The pre-transformation rules file shown below is used to

  • Identify unused local variables declarations and remove them
  • Identify unused import declarations and remove them

This custom transformation cleans up unused local variable declarations and imports, helping in reducing the number of lines that will be considered for transformation as demonstrated in the following example:

custom-transformation-pre-qct.yaml

id: no-unused-vars
language: java
rule:
    kind: local_variable_declaration
    all:
        - has:
              has:
                  kind: identifier
                  pattern: $IDENT
        - not:
              precedes:
                  stopBy: end
                  has:
                      stopBy: end
                      any:
                          - { kind: identifier, pattern: $IDENT }
                          - { has: {kind: identifier, pattern: $IDENT, stopBy: end}}
fix: ''

--- # this is YAML doc separator to have multiple rules in one file

id: no-unused-imports
rule:
    kind: import_declaration
    all:
        - has:
            has:
                kind: identifier
                pattern: $IDENT
        - not:
            precedes:
                stopBy: end
                has:
                    stopBy: end
                    any:
                        - { kind: type_identifier, pattern: $IDENT }
                        - { has: {kind: type_identifier, pattern: $IDENT, stopBy: end}}
fix: ''

The post-transformation rules file serves multiple purposes and helps customers seamlessly upgrade their first-party (1P) dependencies after QCT transforms their application to Java 17 or 21:

  1. When your project uses internal AWS dependencies that have been upgraded to Java 17 or 21, these rules automatically update your POM file to use the latest compatible versions. This eliminates manual dependency version updates and resolves build errors related to private dependencies.
  2. After updating the POM file, the rules automatically modify your code to replace deprecated methods from internal dependencies with their latest supported versions, ensuring compatibility with the upgraded dependencies.
  3. The rules identify System.out.println statements and replace them with a proper logger framework, improving application observability.
    This automated approach significantly simplifies the migration process by handling both the application transformation and internal dependency updates in one streamlined operation.

These rules help modernize your codebase and ensure compatibility with updated dependencies.

custom-transformation-post-qct.yaml

id: update-movie-service-util-java17
language: html
rule:
    pattern: |-
        <dependency>
            <groupId>org.amazonaws.samples</groupId>
            <artifactId>movie-service-utils</artifactId>
            <version>$VERSION</version>
        </dependency>
constraints:
    VERSION:
        regex: "^0\\.1\\.0"
fix: |-
    <dependency>
        <groupId>org.amazonaws.samples</groupId>
        <artifactId>movie-service-utils</artifactId>
        <version>0.2.0</version>
    </dependency>

--- # this is YAML doc separator to have multiple rules in one file
id: update-movie-service-util-method
language: java
rule:
    pattern: |-
        MovieUtils.isValidMovieName($MOVIE_NAME)
fix: |-
    MovieUtils.isValidMovie($MOVIE_NAME, movieId)

--- # this is YAML doc separator to have multiple rules in one file
id: sysout-to-logger
language: java
rule:
    pattern: System.out.println($MATCH)
fix: logger.info($MATCH)

Both pre- and post-transformation enhances logging capabilities, increases configurability, improves error handling, and makes the application more production-ready, while the use of transformation rules automates the process, saving time and reducing errors in large codebases.

Executing the transformation

Now, run the transformation using the Amazon Q Developer CLI:

qct transform --source_folder <path-to-folder>
    --custom_transformation_file <path-to-orchestrator-file> 
    --target_version <your-target-java-version> 

Here,

–source_folder points to the path of the folder containing the Java application that needs to be transformed from version 8 to either 17 or 21.

–custom_transformation_file specifies the path to the orchestrator file (orchestrator_qct_cli.yaml).

–target_version refers to the target Java version to which the application will be transformed. It can be either JAVA_17 or JAVA_21.

If you have common requirements across all the applications you’re transforming, it’s better to store this file in a shared location and use an absolute path during transformation.

For applications with specific requirements, you can include the orchestrator file in the application’s codebase and use a relative path.

Once you execute the transform command if you choose to authenticate with IDC, it will prompt to authenticate providing a URL using the credentials set up in identity center that have access to Amazon Q Developer Pro:
Figure 4: Screenshot showing Amazon Q Developer CLI transform command prompting for IAM Identity Center authentication with a browser verification code
Figure 4: qct transform authentication with the IAM Identity provider

After logging in through the browser, verify if the code matches with the code in the CLI and approve access to Amazon Q Developer.

Once the request is approved – enter Y in the command line to proceed with transformation:

Before starting the transformation, the agent verifies if you have at least the minimum supported version of Maven for transformation

Figure 5: Screenshot of terminal output showing Amazon Q Developer CLI transform command execution, displaying pre-processing steps and transformation job initiation
Figure 5: qct transform starts with pre-processing followed with transformation job

First ast-grep command is run using the pre-transformation template before transformation and once it’s successful, the Q Developer transformation job begins.

Figure 6: Screenshot of terminal showing successful completion of Amazon Q Developer CLI transformation, displaying the newly created Git branch name containing the transformed code
Figure 6: qct transform completed with the results committed to a new branch

After the transformation is complete the changes are saved to a local branch and the branch name can be obtained from CLI output.

After successful transformation ast-grep post-transformation step is executed and the branch is updated with the custom transformed code.

Reviewing and applying the changes

After the transformation is complete, review the changes in the new branch that’s in the CLI output. Use “git branch” to view the new branch created with the transformed files.

git branch

Figure 7: Screenshot of terminal output from 'git branch' command highlighting the newly created branch containing the transformed code
Figure 7: git branch – shows the new branch containing transformation result

Now compare the transformed branch with the source branch in our case its change-branch.

git diff change-branch

Figure 8: Screenshot of Git diff output showing Spring Boot dependency version update from 2.0.5 to 3.3.8 in the project's POM file
Figure 8: Spring boot upgraded to 3.3.8 from 2.0.5

Figure 8: Screenshot of Git diff output showing Java version configuration change from 8 to 17 in the project's build configuration
Figure 9: Java upgraded from 8 to 17

You can see the application is upgraded to Java 17, Spring Boot upgraded to 3.3.0 form 2.0.5, and the internal dependency movie-service-utils upgraded to 0.2.0 version to support Java 17.

Figure 10: Screenshot of Git diff output showing two code changes: removal of unused variables and replacement of System.out.println statements with logger.info calls
Figure 10: Unused variable removed also System.out.println replaced with Logging framework

Figure 11: Screenshot of Git diff output highlighting the removal of unused Java import statements from the source code
Figure 11: Unused imports removed

Figure 12: Screenshot of Git diff output showing MovieUtils.isValidMovie method signature change with updated parameters to align with new dependency version
Figure 12: MobieUtils.isValidMovie method updated to match the updated internal dependency

During pre-transformation

  • Unused local variables are identified and removed from the code.
  • Unused imports are identified and removed

During post-transformation

  • Using custom transformation, the sysout statements are replaced with logger framework.
  • The internal dependency MovieUtils.isValidMovieName method is updated with the required parameters that are required for the latest version using custom post transformation template.

Other changes of the Java 8 to 17 transformation are mentioned here.

Pre-transformation, transformation, and post-transformation changes are committed separately to help users compare differences and identify changes made in each step.

If you’re satisfied with the results, you can create a pull request from the branch which contains the transformed code to your corresponding release branch.

Troubleshooting

When working with Amazon Q Developer CLI transformations, you might encounter some common issues. Here’s how to address them:

  • Unstaged Git Commits
  • Before running a transformation, make sure to stash or commit any pending changes to your local branch. This ensures a clean working directory for the transformation process.
  • Clearing the Working Directory
  • If a transformation fails, clear the workspace located at ~/.aws/qcodetransform/transformation_projects/<your project name> before retrying the transformation. This step is only necessary for failed transformations.

Clean up

To clean up after the transformation:

  • Remove the user or group access to the Amazon Q Developer Pro application
  • Unsubscribe from Amazon Q Developer Pro

Call to Action

Ready to modernize your Java applications? Here’s how to get started:

Conclusion

Using Amazon Q Developer’s CLI capabilities for custom transformations provides a powerful and flexible way to upgrade Java applications. This approach allows you to automate the modernization process, saving time and reducing the risk of manual errors.

By leveraging custom rules, you can tailor the transformation to your specific needs, whether it’s updating deprecated methods, migrating to new APIs, or applying best practices across your codebase.

As you continue to work with Amazon Q Developer, explore more advanced transformation scenarios and integrate this process into your development workflow for ongoing modernization efforts.

About the authors

Profile image for Dinesh Balaaji Prabakaran

Dinesh Balaaji Prabakaran

Dinesh is a Senior Technical Account Manager at AWS based in Richmond, VA. He specializes in supporting Independent Software Vendors (ISVs) on the AWS platform. His expertise includes AWS Generative AI Services, AWS Storage solutions, and architecting event-driven serverless solutions on AWS.

Profile image for Venugopalan Vasudevan

Venugopalan Vasudevan

Venugopalan is a Senior Specialist Solutions Architect at Amazon Web Services (AWS), where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation.

Profile image for Anita Srivastava

Anita Srivastava

Anita Srivastava is a Partner Solutions Architect at Amazon Web Services. She works with a leading Global System Integrator (GSI) to provide architectural guidance and support them in building strategic industry solutions on AWS.

Converting embedded SQL in Java applications with Amazon Q Developer

Post Syndicated from Suruchi Saxena original https://aws.amazon.com/blogs/devops/converting-embedded-sql-in-java-applications-with-amazon-q-developer/

As organizations modernize their database infrastructure, migrating from systems like Oracle to open source solutions such as PostgreSQL is becoming increasingly common. However, this transition presents a significant challenge: discovering and converting embedded SQL within existing Java applications to ensure compatibility with the new database system. Manual conversion of this code is time-consuming, error-prone, and can lead to extended downtime during migration. The process involves cautiously updating numerous SQL statements interwoven in Java code, which can take weeks depending on the application’s size and complexity. This manual approach is highly susceptible to errors, potentially introducing subtle bugs that are difficult to detect. It also requires deep expertise in both source and target database systems. Furthermore, ensuring consistency across the entire codebase during manual conversion is challenging. This can lead to inconsistencies in coding style, performance optimizations, and error handling. These factors combined make the SQL conversion process a significant bottleneck in database migration projects, often delaying modernization efforts and impacting business agility.

Solution

To address these challenges, AWS has introduced an innovative new capability: SQL code conversion using Amazon Q Developer in conjunction with AWS Database Migration Service (AWS DMS). This solution automates the process of transforming embedded SQL in Java applications, significantly reducing the time and effort required for database migrations.
Amazon Q Developer, a generative AI–powered assistant for software development that integrates directly into your Integrated Development Environment (IDE), offers a range of features to enhance developer productivity, including code generation, refactoring, and transformations such as java version upgrades and now SQL code conversion. It analyzes Java code, identifies embedded SQL statements, and automates conversion from the source dialect (e.g. Oracle) to the target dialect (e.g. PostgreSQL). This automation dramatically accelerates the conversion process, potentially reducing weeks of tedious work to just hours of effort.
The solution minimizes human error by leveraging AI algorithms trained on extensive SQL datasets, ensuring a level of consistency and accuracy difficult to achieve manually. It also allows developers to focus on higher-value tasks such as architecture optimization and performance tuning, rather than getting bogged down in the minutiae of SQL syntax differences. When combined with AWS Database Migration Service, which handles schema conversion and data replication, this solution creates a comprehensive migration workflow. It addresses not just code conversion but the entire database migration lifecycle, providing a streamlined path from legacy systems to modern database architectures. By automating SQL conversion, ensuring consistency across the codebase, and integrating with broader migration tools, this feature significantly simplifies the technical aspects of database migration. It aligns with organizational goals of improving efficiency, reducing costs, and maintaining competitiveness in an evolving technological landscape, making it a powerful tool for organizations undertaking database modernization projects.

Overview

To illustrate the power of this solution, let’s consider part of an application written in Java that manages shopping cart functionality for online retail operations using embedded Oracle SQL for database operations. The system allows customers to maintain their shopping carts, manage items, and handle basic e-commerce operations. In our sample application, we look at sections of code from a CartDAO.java class which has multiple Oracle-specific SQL queries. It demonstrates various Oracle-specific SQL features including regular expressions, XML handling, hierarchical queries, and analytical functions. These features make the code particularly optimized for Oracle databases. We’ll need to convert this SQL in order for it to be compatible PostgreSQL. Let’s explore each of these methods.

Method 1:
createItem is a basic insertion method that uses Oracle’s SYSDATE function to automatically timestamp the record. This is Oracle’s built-in function for current date and time.

public void createItem() throws SQLException {
  String sql = "INSERT INTO item (name, description, updated_date) VALUES (?, ?, SYSDATE)";
  Connection conn = getConnection();
  PreparedStatement pstmt = conn.prepareStatement(sql);
  pstmt.setString(1, "Sparkling Water");
  pstmt.setDouble(2, 5.0);
  pstmt.executeUpdate();
  System.out.println("Data inserted successfully");
}

Method 2:
getMfgCodes is a method which uses Oracle’s SUBSTR function to retrieve the first three characters of an item name.

public List<String> getMfgCodes() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT DISTINCT(SUBSTR(name, 1, 3)) AS mfg_code FROM item";
  Statement stmt = conn.createStatement();
  ResultSet rs = stmt.executeQuery(sql);
  List<String> mfg_codes = new ArrayList<String>();
  while (rs.next()) {
    mfg_codes.add(rs.getString("mfg_code"));
  }
  return mfg_codes;
}

Method 3:
findItemsByRegex leverages Oracle’s REGEXP_LIKE function, which provides pattern matching capabilities beyond standard SQL. This is used for complex string searching that would be difficult with simple LIKE clauses.

public List<String> findItemsByRegex(String pattern) throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name FROM item WHERE REGEXP_LIKE(name, ?)";
  PreparedStatement pstmt = conn.prepareStatement(sql);
  pstmt.setString(1, pattern);
  ResultSet rs = pstmt.executeQuery();
  List<String> names = new ArrayList<String>();
  while (rs.next()) {
    names.add(rs.getString("name"));
  }
  return names;
}

Method 4:
cleanItemDescriptions uses Oracle’s advanced regular expression capabilities through REGEXP_REPLACE. It specifically uses Oracle’s character class syntax [[:punct:]] to identify punctuation marks, which is an Oracle-specific implementation of POSIX regular expressions.

public void cleanItemDescriptions() throws SQLException {
  Connection conn = getConnection();
  String sql = "UPDATE item SET description = REGEXP_REPLACE(description, " 
               +" '([[:punct:]]{2,}|\\s{2,})', ' ') "
               +" WHERE REGEXP_LIKE(description, '([[:punct:]]{2,}|\\s{2,})') ";   
  try (Statement stmt = conn.createStatement()) {
  int rowsUpdated = stmt.executeUpdate(sql);
  System.out.println("Cleaned descriptions for " + rowsUpdated + " items");
  }
}

Method 5:
This function retrieves the top 3 most expensive items for each premium category from the ‘item’ table using Oracle’s analytical RANK() function. It creates a formatted string for each item containing the premium category, item name, price, and its rank within its category. The results are stored in a List and returned.

public List<String> getTopItemsByCategory() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT * FROM (SELECT name, premium, price,RANK() OVER (PARTITION BY premium"
               +" ORDER BY price DESC) as price_rank FROM item) WHERE price_rank <= 3";
  List<String> topItems = new ArrayList<>();
  try (Statement stmt = conn.createStatement();
    ResultSet rs = stmt.executeQuery(sql)) 
    while (rs.next()) {
      String result = String.format("Premium: %s, Item: %s, Price: %.2f, Rank: %d",
      rs.getString("premium"),
      rs.getString("name"),
      rs.getDouble("price"),
      rs.getInt("price_rank"));
      topItems.add(result);
    }
  }
  return topItems;
}

Method 6:
The SQL query in the findItemsByPriceRange method performs a targeted search and ranking operation on the item table in the database. It begins by filtering items to only those within a specific price bracket.

public List<String> findItemsByPriceRange() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name, price, RANK() OVER (ORDER BY price) as price_rank FROM item"
               + "WHERE price BETWEEN ? AND ?";
  List<String> items = new ArrayList<>();
  try (PreparedStatement pstmt = conn.prepareStatement(sql)) {
    pstmt.setDouble(1, 50.0);
    pstmt.setDouble(2, 75.0);
    ResultSet rs = pstmt.executeQuery();
    while (rs.next()) {
      String result = String.format("Item: %s, Price: %.2f, Rank: %d",
      rs.getString("name"),
      rs.getDouble("price"),
      rs.getInt("price_rank"));
      items.add(result);
    }
  }
  return items;
}

Method 7:
This function demonstrates Oracle’s ROWNUM pseudo-column, which is a specific Oracle database feature used to limit the number of rows returned by a query. The function retrieves the first N items from the ‘item’ table by using ROWNUM <= ? in the WHERE clause.

public List<String> getFirstNItems(int n) throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name FROM item WHERE ROWNUM <= ?";
  List<String> items = new ArrayList<>();
  try (PreparedStatement pstmt = conn.prepareStatement(sql)) {
    pstmt.setInt(1, n);
    ResultSet rs = pstmt.executeQuery();
    while (rs.next()) {
      items.add(rs.getString("name"));
    }
  }
  return items;
}

Our goal is to convert these embedded Oracle specific queries to PostgreSQL queries.

Solution Walkthrough

Prerequisites

Before beginning the conversion process, ensure you have installed and configured Amazon Q in your IDE by following the setup guide. Your source codebase must be a Java application containing embedded Oracle SQL statements that you plan to migrate to PostgreSQL. The transformation specifically targets Oracle SQL syntax within Java code, so verify your application meets these requirements. Complete your database schema migration using AWS DMS Schema Conversion before starting the code transformation process. This crucial step creates the foundation for your PostgreSQL database structure.

Convert Embedded SQL

Open your Java application containing embedded SQL statements in your IDE where Amazon Q is installed. Access the Amazon Q chat panel by selecting the Amazon Q icon in your IDE interface. Start the transformation process by typing /transform in the chat panel. When prompted, specify ‘SQL conversion’ as your transformation type. Amazon Q validates your Java application’s eligibility for SQL conversion before proceeding.

Initiating SQL conversion in the Q chat panel. Open the Amazon Q chat panel. Enter “/transform” in the chat panel. Enter “SQL conversion” when prompted.

Upload your schema metadata file when prompted by Amazon Q. The chat interface provides detailed instructions for retrieving this file from your previous DMS schema conversion process. Select your project containing embedded SQL and the corresponding database schema file from the dropdown menus in the chat panel. Amazon Q displays the detected database schema details for your confirmation. Take a moment to verify these details are accurate before proceeding with the conversion.

Uploading schema metadata file and verifying the detected database schema details for conversion.

The SQL conversion process would begin, during which Amazon Q analyzes and transforms your Oracle SQL statements into PostgreSQL-compatible syntax.

Amazon Q analyzes and transforms Oracle SQL statements into PostgreSQL-compatible syntax.

For this application, Amazon Q was able to detect 7 Oracle specific queries in the code and was able to process them to the corresponding PostgreSQL queries. It generated a conversion summary of the embedded SQL statements processed, and shared recommended actions for 2 queries that needed further inspection.
Amazon Q presented a comprehensive diff view showing all proposed changes to the embedded SQL. Review each modification in the diff view carefully. After your review, accept the changes to update your codebase. Amazon Q generates a detailed transformation summary documenting all modifications made during the conversion.

Reviewing proposed code changes and accepting them.

Let’s take a look at how each of SQL statements within each function got converted to be compatible with PostgreSQL.

Method 1:
The key difference in this query involves the transition from Oracle’s SYSDATE function to PostgreSQL’s CLOCK_TIMESTAMP() with time zone handling. While SYSDATE in Oracle returns the current date and time of the database server, the PostgreSQL version uses CLOCK_TIMESTAMP() which provides the actual current time and explicitly handles timezone conversion through AT TIME ZONE.

public void createItem() throws SQLException {
    String sql = "INSERT INTO admin.item (name, description, updated_date) VALUES (?, ?,    
                 (CLOCK_TIMESTAMP() AT TIME ZONE COALESCE(CURRENT_SETTING('aws_oracle_ext.tz', 
                 TRUE), 'UTC'))::TIMESTAMP(0))";
    Connection conn = getConnection();
    PreparedStatement pstmt = conn.prepareStatement(sql);
    //pstmt.setInt(1, 1);
    pstmt.setString(1, "Sparkling Water");
    pstmt.setDouble(2, 5.0);
    pstmt.executeUpdate();
    System.out.println("Data inserted successfully");
}

Method 2:
The key change in the next query involves using an extension pack added by the DMS Schema Conversion process which emulates source database functions. This is referenced using the fully qualified function name aws_oracle_ext.substr instead of the simple SUBSTR. The aws_oracle_ext schema contains Oracle-compatible functions to maintain compatibility with Oracle SQL syntax. Additionally, the table reference has been made more specific by including the schema name admin.item instead of just item, which helps avoid ambiguity in multi-schema environments.

public List<String> getMfgCodes() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT DISTINCT (aws_oracle_ext.substr(name, 1, 3)) AS mfg_code FROM 
                admin.item";
  Statement stmt = conn.createStatement();
  ResultSet rs = stmt.executeQuery(sql);
  List<String> mfg_codes = new ArrayList<String>();
  while (rs.next()) {
    mfg_codes.add(rs.getString("mfg_code"));
  }
  return mfg_codes;
}

Method 3:
The next transformation demonstrates several important adaptations required for Oracle-compatible regular expression functionality in AWS. The key changes include: REGEXP_LIKE function has been replaced with its AWS Oracle extension equivalent aws_oracle_ext.regexp_like. Explicit type casting to TEXT has been added using the PostgreSQL-style cast operator:: TEXT for both the column name and the parameter. The schema qualifier admin has been added to the table name and extra parentheses have been added around the arguments for proper type handling. These modifications ensure that regular expression pattern matching works correctly in the AWS environment while maintaining Oracle-like functionality. The explicit TEXT type casting is particularly important as it ensures proper data type handling during the regular expression comparison operations.

public List<String> findItemsByRegex(String pattern) throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name FROM admin.item WHERE aws_oracle_ext.regexp_like((name)::TEXT,
               (?::TEXT)::TEXT)";
  PreparedStatement pstmt = conn.prepareStatement(sql);
  pstmt.setString(1, pattern);
  ResultSet rs = pstmt.executeQuery();
  List<String> names = new ArrayList<String>();
  while (rs.next()) {
    names.add(rs.getString("name"));
  }
  return names;
}

Method 4:
The next conversion shows several sophisticated adaptations required for Oracle-compatible regular expression functionality. The changes include the addition of the aws_oracle_ext schema prefix to both regexp_replace and regexp_like functions. The introduction of the E prefix before string literals containing escape sequences, which is PostgreSQL’s syntax for enabling escape sequence interpretation. Additional escaping of backslashes (from \s to \\s) has been added to properly handle whitespace matching in the AWS environment. Explicit type casting to TEXT using ::TEXT has been added for all arguments in both the regexp_replace and regexp_like functions. The schema qualifier admin has been added to the table name. Single quotes around the replacement space character have been wrapped with parentheses. These modifications ensure that the regular expression replacement and matching operations work correctly in the AWS environment while maintaining Oracle-like functionality. The pattern itself is designed to replace multiple consecutive punctuation marks or whitespace characters with a single space character.

public void cleanItemDescriptions() throws SQLException {
  Connection conn = getConnection();
  String sql = "UPDATE admin.item SET description = 
                aws_oracle_ext.regexp_replace((description)::TEXT, 
                (E'([[:punct:]]{2,}|\\\\s{2,})')::TEXT, 
                ('')::TEXT) WHERE aws_oracle_ext.regexp_like((description)::TEXT,   
                (E'([[:punct:]]{2,}|\\\\s{2,})')::TEXT)";  
  try (Statement stmt = conn.createStatement()) {
    int rowsUpdated = stmt.executeUpdate(sql);
    System.out.println("Cleaned descriptions for " + rowsUpdated + " items");
  }
}

Method 5:
The next transformation shows a few key modifications required for proper execution in PostgreSQL. The addition of an explicit alias AS var_sbq for the derived subquery, which is required in PostgreSQL systems to properly reference derived tables The schema qualifier admin has also been added to the table name item.

public List<String> getTopItemsByCategory() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT * FROM (SELECT name, premium, price, RANK() OVER (PARTITION BY 
                premium ORDER BY price DESC) AS price_rank FROM admin.item) AS var_sbq WHERE 
                 price_rank <= 3";
  List<String> topItems = new ArrayList<>();
  try (Statement stmt = conn.createStatement();
    ResultSet rs = stmt.executeQuery(sql)) {   
      while (rs.next()) {
        String result = String.format("Premium: %s, Item: %s, Price: %.2f, Rank: %d",
        rs.getString("premium"),
        rs.getString("name"),
        rs.getDouble("price"),
        rs.getInt("price_rank"));
        topItems.add(result);
      }
    }
  return topItems;
}

Method 6:
The next transformation demonstrates a few important modifications for PostgreSQL compatibility: The addition of explicit type casting using ::NUMERIC for both parameters in the BETWEEN clause, which ensures proper numeric comparison and helps prevent type conversion issues The schema qualifier admin has been added to the table name item The window function RANK() syntax remains unchanged as it’s standard ANSI SQL.

public List<String> findItemsByPriceRange() throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name, price, RANK() OVER (ORDER BY price) AS price_rank FROM 
                admin.item WHERE price BETWEEN ?::NUMERIC AND ?::NUMERIC";
  List<String> items = new ArrayList<>();
  try (PreparedStatement pstmt = conn.prepareStatement(sql)) {
    pstmt.setDouble(1, 50.0);
    pstmt.setDouble(2, 75.0);
    ResultSet rs = pstmt.executeQuery();
    while (rs.next()) {
      String result = String.format("Item: %s, Price: %.2f, Rank: %d",
      rs.getString("name"),
      rs.getDouble("price"),
      rs.getInt("price_rank"));
      items.add(result);
    }
  }
  return items;
}

Method 7:
The next transformation shows several significant changes for PostgreSQL compatibility. The Oracle-specific ROWNUM syntax has been replaced with the standard SQL LIMIT clause. A CASE expression has been added to handle input validation. TRUNC(?::NUMERIC) converts the input parameter to a numeric value and removes any decimal places. The CASE statement ensures that only positive numbers are accepted. If the input is less than or equal to 0, it returns 0 (effectively no rows). The schema qualifier admin has been added to the table name. The parameter is now used twice in the query (once for comparison and once for the actual limit). Type casting to NUMERIC has been added for safer numeric handling.

public List<String> getFirstNItems(int n) throws SQLException {
  Connection conn = getConnection();
  String sql = "SELECT name FROM admin.item LIMIT CASE WHEN TRUNC(?::NUMERIC) > 0 THEN 
                 TRUNC(?::NUMERIC) ELSE 0 END";
  List<String> items = new ArrayList<>();
  try (PreparedStatement pstmt = conn.prepareStatement(sql)) {
    pstmt.setInt(1, n);
    ResultSet rs = pstmt.executeQuery();
    while (rs.next()) {
      items.add(rs.getString("name"));
    }
  }
  return items;
}

End-to-End Testing

After completing the SQL code conversion, update your application’s database connection settings to point to your new PostgreSQL database. This includes modifying connection strings, updating database credentials, and adjusting any database-specific configuration parameters.
Execute your application’s comprehensive test suite to validate the converted SQL statements. The test suite should cover all database interactions, ensuring queries return expected results and maintain proper data integrity. Pay particular attention to complex queries, stored procedure calls, and transaction management scenarios. Conduct thorough testing of your application’s critical paths. Focus on core business workflows that heavily depend on database operations. Test edge cases and error conditions to verify proper exception handling with the new PostgreSQL database. As a best practice recommendation, implement detailed monitoring of your application logs during testing. Watch for any SQL-related errors, unexpected query behavior, or performance degradation.

Conclusion

The combination of Amazon Q Developer and AWS DMS represents a significant leap forward in database migration technology. By automating the conversion of embedded SQL, we’ve addressed one of the most time-consuming and error-prone aspects of moving from Oracle to PostgreSQL.

Key benefits of this approach include:

  • Reduced migration time: What once took weeks can now be accomplished in days or hours
  • Improved accuracy: AI-powered conversion minimizes human error
  • Cost savings: Less developer time spent on manual code updates shortening modernization and upgrade initiatives
  • Seamless integration: Works within your existing development environment

As organizations continue to modernize their database infrastructure, services like Amazon Q Developer will play a crucial role in ensuring smooth, efficient migrations. By leveraging the power of AI to handle complex code transformations, developers can focus on adding value to their applications rather than getting bogged down in the intricacies of SQL dialect differences. We encourage you to try Amazon Q Developer using the Amazon Q User Guide for your next database migration project and experience firsthand the benefits of automated SQL code conversion.

About the Authors

Suruchi Saxena

Suruchi Saxena is a Senior Cloud/DevOps Engineer working at Amazon Web Services, where she combines her expertise in Generative AI and DevOps to deliver transformative solutions for enterprise customers. She specializes in architecting and managing cloud-based solutions, automation, code delivery and analysis, infrastructure as code. She focuses on streamlining development operations while leveraging advanced AI capabilities to deliver innovative solutions for complex enterprise challenges.

Jason Varghese

Jason is a Senior Solutions Architect at AWS guiding enterprise customers on their cloud migration and modernization journeys. He has served in multiple engineering leadership roles and has over 20 years of experience architecting, designing and building scalable software solutions. Jason holds a bachelor’s degree in computer engineering from the University of Oklahoma and an MBA from the University of Central Oklahoma.

Venugopalan Vasudevan

Venugopalan Vasudevan is a Senior Specialist Solutions Architect at Amazon Web Services, where he specializes in AWS Generative AI services. His expertise lies in helping customers leverage cutting-edge services like Amazon Q, and Amazon Bedrock to streamline development processes, accelerate innovation, and drive digital transformation. Venugopalan is dedicated to facilitating the Next Generation Developer experience, enabling developers to work more efficiently and creatively through the integration of Generative AI into their workflows.

Announcing support for upgrades to Java 21 in Amazon Q Developer

Post Syndicated from Brian Beach original https://aws.amazon.com/blogs/devops/announcing-support-for-upgrades-to-java-21-in-amazon-q-developer/

On February 14, Amazon Q Developer announced support for upgrades to Java 21. As a Java developer, I’m excited about this new capability, which will make it easier for me to keep my applications up-to-date and take advantage of the latest language features and performance improvements. In addition, the latest version of Amazon Q Developer includes improved summarization and recommendations that simplify the upgrade process and increase confidence in the results.

Amazon Q Developer is a generative AI-powered assistant that helps accelerate the modernization of enterprise applications. It can perform complex tasks like analyzing legacy code, mapping dependencies, and executing migration and modernization workflows. Amazon Q Developer frees up your team to focus on more strategic initiatives rather than getting bogged down in the undifferentiated heavy lifting of upgrading Java applications.

Staying current on Java versions is crucial, as each new release brings important security fixes, performance enhancements, and support for emerging frameworks and libraries. However, the effort required to manually migrate large Java codebases can be daunting. That’s where Amazon Q Developer has been invaluable. By offloading the tedious, labor-intensive parts of the upgrade process, your team can deliver important updates to users much faster while minimizing disruption.

The Benefits of Java 21

With the addition of Java 21 upgrade capabilities, Amazon Q Developer now supports upgrading applications from Java 8, 11, and 17 to Java 17 or 21. Some of the key benefits of Java 21 that I’m looking forward to include:

Virtual Threads: Virtual Threads are a new concurrency primitive introduced in Java 19 that reduce the effort of writing, maintaining, and debugging high-throughput concurrent applications. This unlocks significant performance improvements for your applications.

Improved Performance: Java 21 includes a variety of other language enhancements like Sequenced Collections, Record Patterns, and Pattern Matching that deliver tangible speed and efficiency gains.

Better Memory Management: Enhancements to the Z Garbage Collector in Java 21 result in more predictable garbage collection pauses and reduced memory footprint, leading to more stable and responsive applications.

Upgrading your team’s Java applications to Java 21 with Amazon Q Developer is a game-changer. It saves countless hours of manual effort that would otherwise be required to migrate all of your Java components.

Simplifying the Upgrade Process with Amazon Q Developer

Upgrading Java applications to Java 21 with Amazon Q Developer is easy. After configuring your project and ensuring it meets the prerequisites, you can simply invoke the /transform command in the Amazon Q Developer chat window of your integrated development environment (IDE). The following screenshot is from VS Code; however, Q Developer also supports JetBrain’s IDEs including IntelliJ IDEA and the qct command line.

Q Code Transformation dialog showing Java 17 selected as the source version and Java 21 selected as the target version.

Amazon Q Developer will then analyze your codebase, determine the necessary changes to upgrade to Java 21, and provide a detailed diff so you can review and accept the transformations. This not only saves you time, but also helps ensure a consistent, high-quality upgrade across all of your Java applications.

In addition to adding support for upgrading to Java 21, the latest version of Amazon Q Developer also enhances the summarization and recommendations it provides after completing the transformation. Once the upgrade to Java 21 is complete, Q Developer generates a detailed summary of the changes made, such as deprecated APIs removed and code refactored to leverage new Java features. It also includes tailored recommendations to further improve the application, taking advantage of the capabilities introduced in Java 21. For example, Q Developer suggested upgrading the logging framework and implementing pattern matching to make the code more concise. These summary and recommendation capabilities help ensure a smooth and comprehensive upgrade process.

A summary screen showing five key changes made during a transformation process, including Maven compiler updates to Java 21, POM file modifications, and retained dependencies. The text appears in white against a dark background and details technical configurations involving Maven, JUnit, and Surefire plugin settings.

Finally, Q includes recommendations to further improve the application beyond the upgrade to Java 21. For example, Q provided the following recommendations.

A recommendations screen with three items for improving a software upgrade. The text is white on a dark background and includes advice on reviewing code changes, re-enabling Maven plugins, and using Amazon Q chat in the IDE for further code transformation assistance.

The summary and recommendation capabilities help ensure a smooth and comprehensive upgrade experience. Developers can review the detailed changes, understand the rationale behind them, and then selectively apply the suggested optimizations to fully unlock the benefits of Java 21. This level of transparency and guidance from Q Developer greatly simplifies the upgrade process and increases confidence in the resulting codebase.

Conclusion

In summary, the new Amazon Q Developer transformation capabilities for upgrades to Java 21 offload the labor-intensive task of keeping your Java applications up-to-date. The detailed summaries and tailored recommendations provided by Q Developer ensure a smooth and comprehensive upgrade process, and significantly streamline the upgrade process. I’m excited to start rolling this out and freeing up the team’s time to focus on higher-value work. If you’re a fellow Java developer, I’d highly encourage you to try out Amazon Q Developer for yourself. To get started, visit the Amazon Q Developer getting started page.

Leverage powerful generative-AI capabilities for Java development in the Eclipse IDE public preview

Post Syndicated from Vinicius Senger original https://aws.amazon.com/blogs/devops/amazon-q-developer-eclipse-preview/

Today marks an exciting milestone for Eclipse developers everywhere: we’re thrilled to announce the public preview of Amazon Q Developer in the Eclipse IDE. This integration brings the power of AI-driven development directly into one of the most popular development environments. In this blog post, we’ll explore some of its game-changing features, and show you how this fusion of traditional IDE and cutting-edge AI can supercharge your development tasks across the software development lifecycle.

Background

As I sit down to write this announcement, I can’t help but feel a wave of nostalgia mixed with excitement. This is one of the most requested IDEs for Amazon Q Developer and I can see why. Like many developers of my generation, Eclipse was where I cut my teeth in Java programming. I remember downloading that bulky IDE, waiting for what felt like an eternity as it installed, and then staring at the workspace, both intimidated and thrilled by the possibilities it presented.

Eclipse has been a stalwart in the world of software development for over two decades now. It’s been there through the evolution of Java, from the early days of J2SE to the modern Java Platform. For countless developers, it’s been more than just an IDE – it’s been a trusty companion on our coding journeys.

But times have changed. The landscape of software development is evolving at a rapid pace, and at the heart of this revolution is Generative AI. We’re witnessing a paradigm shift in how we approach coding, testing, and deploying applications. And today, I’m thrilled to announce a game-changing integration that brings together the familiar comfort of Eclipse with the cutting-edge capabilities of Amazon Q Developer.

Introducing Amazon Q Developer plugin for Eclipse IDE

Amazon Q Developer is the most capable AI-powered assistant for software development that reimagines the experience across the entire software development lifecycle, making it easier and faster to build, secure, manage, and optimize applications on AWS. By bringing this powerhouse directly into Eclipse, we’re not just adding a feature – we’re opening up a new world of possibilities for Java developers. Whether you’re a seasoned Java veteran or just starting your development journey, Amazon Q Developer in Eclipse is set to become your indispensable generative AI-assistant that accelerates tasks across the software development lifecycle, including coding.

During the public preview, Eclipse developers will be able to chat with Amazon Q Developer about their project and code faster with inline code suggestions. By leveraging Amazon Q Developer customizations they’ll be able to receive tailored responses that conform to their team’s internal tools and services, helping developers build faster while enhancing productivity across the entire software development lifecycle. Let’s take a look at some of the features that will be available to you during public preview.

Inline suggestions

Inline code suggestions is an excellent starting point for experiencing Amazon Q Developer AI-powered capabilities. As you type, Amazon Q Developer analyzes your code, comments, and naming conventions to provide context-aware suggestions. Note, that the more comprehensive and well-organized your code documentation is, the more accurate and helpful Amazon Q Developer’s suggestions will be.

Amazon Q is using a class with pre-existing methods as context for the inline code suggestions.

Chat

The Amazon Q Developer chat interface serves as a versatile tool for various development needs. You can request code snippet suggestions, ask questions about your project, or seek guidance on implementing specific functionalities. For example, you could ask for sample code to calculate a Fast Fourier Transform in Java or seek assistance in enhancing a database class with additional fields using UUID.

Seeking guidance from Amazon Q Developer on how to apply Fast Fourier transform with Java to detect frequencies.

You can also seamlessly integrate code snippets into your chat interactions with Amazon Q Developer. By selecting a code fragment and sending it to the chat window (by right-clicking in the editor and selecting Amazon Q > Send To Prompt), you can ask specific questions about the code or request modifications, enabling a more interactive and context-aware coding experience.

Integrate code snippets by using the right-click menu to ask Amazon Q Developer to integrate it into your chat experience.

You can also use the right-click menu to ask Amazon Q Developer to explain, refactor, fix, or optimize a selected fragment of code.

Customization

With customizations, Amazon Q Developer can assist with software development in ways that conform to your team’s internal libraries, proprietary algorithmic techniques, and enterprise code style. Customizations must first be configured by an administrator; they can then be selected in the IDE using the menu in the Amazon Q Developer panel. For more information, please refer to the user guide.

Conclusion

The Amazon Q Developer plugin for Eclipse IDE preview represents a significant step forward in enhancing the development experience within this trusted platform. By integrating AI-powered tools such as inline suggestions and chat, Amazon Q Developer empowers developers to work more efficiently across different programming tasks. Whether you’re maintaining legacy code, building new features, or troubleshooting complex issues, Amazon Q Developer streamlines your workflow, allowing you to focus on what matters most — writing great code.

To get started, install the Amazon Q Developer plugin into your Eclipse IDE.

Dissecting the Performance Gains in Amazon Q Developer agent for code transformation

Post Syndicated from Jonathan Vogel original https://aws.amazon.com/blogs/devops/dissecting-the-performance-gains-in-amazon-q-developer-agent-for-code-transformation/

Amazon Q Developer Agent for code transformation is an AI-powered tool which modernizes code bases from Java 8 and Java 11 to Java 17. Integrated into VS Code and IntelliJ, Amazon Q simplifies the migration process and reduce the time and effort compared to manual process. It proposes and verifies code changes, using AI to debug compilation errors. In this blog post, we’ll explore recent improvements to our code transformation agent, particularly its enhanced debugging capabilities. The enhanced debugger agent significantly improves transformation efficiency and quality compared to the existing debugger.

How Amazon Q transforms Java applications

To upgrade Java codebases, the code transformation agent takes the source code input and verify the build and test in source Java version. It then uses deterministic tools to apply code changes, followed by building and testing the changed code in the target Java version. If errors occur in this stage, a generative AI-based system debugs and resolves the compilation errors. Until today, the debugger resolves each error one by one, locating the code file with the error in the codebase, and fixing it. This debug step iterates until all compilation errors are solved or the maximum number of iterations is reached.

A flowchart diagram illustrating Amazon Q's code transformation process for accelerating Java upgrades to version 17. The workflow begins with source code input, flowing through a transformation engine that applies deterministic tools and generative AI, followed by build/test verification cycles and AI-powered debugging to resolve any compilation errors.

As an example, if, as the result of a library upgrade, an import statement is missing or wrong, the AI debugger will re-build, iterate to find all the references in multiple files one by one, and update each reference to resolve the error. Refer to this blog “Three ways Amazon Q Developer agent for code transformation accelerates Java upgrades” for detailed explanation of each transformation step. This approach has helped Q Developer customers achieve accelerations of migration effort by over 40%.

Improving the debugging capabilities of code transformations

To further improve the ability of Q Developer to generate error-free code, we’ve just released multiple foundational improvements to the AI debugger.

  • Multi-error context: the debug AI can now take multiple build errors into consideration, which provides more context, leading to better solution discovery.
  • More tools available for the AI: compared to simply localizing error to a single file and fixing the error previously, the agent can now execute multi-file solutions by exploring the codebase and operating on multiple files.
  • Inter-iteration memory: the debugger AI now remembers previous errors, which contributes to debugging new errors.
  • Intelligent backtracking: the debugger AI can now recognize if the current solution path leads to a dead end, in which case the agent can roll back to the previous state.

To implement these capabilities, the debugger AI is re-architected as a multi-agent system. A memory management agent is responsible to analyze last iteration results and append the relevant portions to the inter-iteration memory. A critic agent is responsible to analyze progress and provide additional information to the debugger agent and, if a dead end is detected, rollback the progress to a previous state. A debugger agent, analyzes the memory and the critique from the previous agents and modifies or updates the plan to fix the remaining errors in the codebase. The debugger agent has its disposal a set of generic and specialized tools to browse and explore the codebase, edit source files, trigger builds, add dependencies, and so on. It is important to note that the agent only has access to the files and tools related to the transformation task, which limits hallucinations and drive towards progress.

Let’s examine how the agent handles recurring issues across multiple files with these improvements. Consider a scenario where several Java files are missing the same import statement after upgrading from Java 8 to Java 17. This happens when you upgrade from older Java collections (like Vector and Enumeration) to modern streaming operations. The system is capable of helping you update these patterns automatically. The agent is now able to intelligently detect this pattern and implement a comprehensive solution across all affected files. Suppose we have three Java files that use the java.util.stream.Collectors class, but the import is missing in each:

File1.java:

public class File1 {
    public List<String> process(List<String> input) {
        return input.stream()
            .filter(s → s.length() > 5)
            .collect(Collectors.toList()); // Error: Cannot resolve symbol 'Collectors'
    }
}

File2.java:

public class File2 {
    public Map<String, Long> countWords(List<String> words) {
        return words.stream()
            .collect(Collectors.groupingBy(
                word -> word.toLowerCase(),
                Collectors.counting()
            )); // Error: Cannot resolve symbol 'Collectors'
    }
}

File3.java:

public class File3 {
    public String concatenate(List<String> strings) {
        return strings.stream()
            .collect(Collectors.joining(", "));
            // Error: Cannot resolve symbol 'Collectors'
    }
}

After the agent detects the common issue and applies the fix, all three files would be updated as follows:

File1.java (after fix):

import java.util.stream.Collectors;

public class File1 {
    public List<String> process(List<String> input) {
        return input.stream()
            .filter(s -> s.length() > 5)
            .collect(Collectors.toList());
    }
}    

File2.java (after fix):

import java.util.stream.Collectors;

public class File2 {
    public Map<String, Long> countWords(List<String> words) {
        return words.stream()
            .collect(Collectors.groupingBy(
                word -> word.toLowerCase(),
                Collectors.counting()));
    }
}

File3.java (after fix):

import java.util.stream.Collectors;

public class File3 {
    public String concatenate(List<String> strings) {
        return strings.stream()
            .collect(Collectors.joining(", "));
    }
}

In this example, the agent has identified that the same import statement (import java.util.stream.Collectors;) was missing in all three files. It then applied the fix consistently across all affected files, demonstrating its ability to recognize patterns and implement solutions efficiently across the entire codebase, avoiding different solutions attempts for each individual error, and saving iteration budget to solve different errors, if present.

The contrast between existing debugger and enhanced Agent is more clear when handling complex, interconnected changes. For instance, in updating Springfox Swagger from 2.0 to 3.0 (OpenAPI), both systems initially made similar changes. However, when faced with subsequent errors, their approaches diverged significantly. Consider this scenario:
Initially, both systems removed Springfox dependencies:

<!-- Removed by both systems -->
<dependency>
    <groupId>io.springfox</groupId>
    <artifactId>springfox-swagger2</artifactId>
    <version>2.9.2</version>
</dependency>

Later, when encountering a “missing symbol: Docket” error, existing debugger attempted to reintroduce Springfox:

<!-- existing debugger trying to add back Springfox -->
<dependency>
    <groupId>io.springfox</groupId>
    <artifactId>springfox-boot-starter</artifactId>
    <version>3.0.0</version>
</dependency>

In contrast, our Agent recognized this as consistent with the previous removal and rewrote the file using SpringDoc OpenAPI:

import org.springdoc.core.GroupedOpenApi;

@Configuration
public class SwaggerConfig {
    @Bean
    public GroupedOpenApi publicApi() {
        return GroupedOpenApi.builder()
                .group("springshop-public")
                .pathsToMatch("/public/**")
                .build();
    }
}   

These latest improvements in our debug AI have yielded positive results. By incorporating multi-error context analysis, additional tooling of multi-file solution, and inter-iteration memory, the agent now delivers more comprehensive and consistent codebase upgrades. We tested our new approach on 62 large open-source applications, some containing over 100,000 lines of code, incorporating more than 100 open-source libraries. The results showed an 85% higher success rate compared to the previous approach. These enhancements significantly boost both the quality and efficiency of code transformation, marking a substantial leap forward in automated application modernization for Java.

Conclusion

With the latest improvements, Q Developer continues to accelerate the journey to modernize Java applications across your organization. For more context, please refer to the blog “Accelerate application upgrades with Amazon Q Developer agent for code transformation.”

As we continue to innovate in code transformation use cases, this release creates the foundation to expand language support, further enhance AI-driven problem-solving algorithms, and streamlining the integration with development workflows. Our goal remains to provide developers and organizations with cutting-edge tools that simplify complex maintenance and modernization processes and foster the adoption of modern, cloud-native architectures. Stay tuned for future updates as we push the boundaries of AI-assisted code transformation.

About the authors

Omer Tripp

Omer heads the Q Code Transformation science team. His research work is at the intersection of programming languages and AI/ML, emphasizing developer productivity and acceleration as well as software security and reliability. Outside of work, Omer likes to stay physically active (through tennis, basketball, skiing, and various other activities), as well as tour the US and the world with his family.

Jonathan Vogel

Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.

Yiyi Guo

Yiyi is a Senior Product Manager at AWS working on Amazon Q developer agent for code transformation, she focuses on leveraging generative AI to accelerate enterprise application modernization.

Elio Damaggio

Elio Damaggio is the product lead for the transformation capabilities of Amazon Q Developer. With more than 15 years in tech, 11 patents, and a PhD in Computer Science, he is now looking for exciting ways to empower developers through AI.

Special thanks to the scientists on the Q Developer team who helped to provide input to this blog: Talha Oz and Zeren Shui.

Diving Deeper into Projen: Exploring Advanced Features

Post Syndicated from Michael Tran original https://aws.amazon.com/blogs/devops/diving-deeper-into-projen-exploring-advanced-features/

We will be highlighting Projen’s powerful features that cater to various aspects of project management and development. We’ll examine how Projen enhances polyglot programming within Amazon Web Services (AWS) Cloud Development Kit constructs. We’ll also touch on its built-in support for common development tools and practices.

In our previous blog, we introduced you to the basics of getting started with Projen. Projen is a powerful project generator that simplifies the management of complex software configurations. In our prior blog, we discussed developing a new AWS cloud development kit (CDK) construct library project. For consistency, we will continue using this construct library project as our example while exploring linting, dependency management, and test coverage. It’s important to note that these practices are equally applicable to CDK applications and other project types.

AWS CDK Polyglot Construct Library

The AWS Cloud Development Kit (AWS CDK) is an open-source software development framework that allows developers to define cloud infrastructure using familiar programming languages. In a CDK application, constructs serve as the foundational elements, allowing developers to represent either a single AWS resource or a complex combination of resources. These constructs are not only reusable but can be incorporated into other AWS CDK projects, promoting efficient and scalable development practices.

Projen and Polyglot Programming

Projen leverages the power of the JSII library, enabling developers to write constructs once and generate equivalent constructs across multiple programming languages. This feature streamlines the development process, especially when working with teams that have expertise in different languages.

Automated Publishing with Projen

With its publisher module, Projen automates the distribution of c
ructs to various package managers. This process can be integrated into a GitHub workflow, such as a build job, which triggers the publication of the library to the designated package managers.

Starting with Projen

Initiating an AWS CDK construct library project is straightforward through the Projen command npx projen new <project_type>. By executing the command npx projen new awscdk-construct, you initialize a new project complete with a projenrc file. This file contains the essential configuration for a CDK construct library, setting the stage for further customization and development.

import { awscdk } from 'projen';
const project = new awscdk.AwsCdkConstructLibrary({
  author: 'github username',
  authorAddress: 'github email',
  cdkVersion: '2.1.0',
  defaultReleaseBranch: 'main',
  jsiiVersion: '~5.0.0',
  name: 'cdkconstruct',
  projenrcTs: true,
  repositoryUrl: 'https://github.com/*****/cdkconstruct.git',

  // deps: [],                /* Runtime dependencies of this module. */
  // description: undefined,  /* The description is just a string that helps people understand the purpose of the package. */
  // devDeps: [],             /* Build dependencies for this module. */
  // packageName: undefined,  /* The "name" in package.json. */
});
project.synth();

A release.yml file is generated by projen under the github>workflow directory. This file has the details of the public registry where the construct needs to be published. By default, it will add the details for npm.

release_npm:
    name: Publish to npm

The construct can be developed in typescript under src/main.ts, our previous blog shows how to create one. If the construct needs to be published to other public registries (such as Maven for java, Pypi for python), then a projenrc file can be updated to synthesize a new release.yml file.

For example, to publish a construct developed in typescript to Maven (so that it can be used in a java application) add publishToMaven API to the projenrc file.

const project = new awscdk.AwsCdkConstructLibrary({
  author: 'github username',
  authorAddress: 'github email',
  cdkVersion: '2.1.0',
  defaultReleaseBranch: 'main',
  jsiiVersion: '~5.0.0',
  name: 'cdkconstruct',
  projenrcTs: true,
  repositoryUrl: 'https://github.com/*****/cdkconstruct.git',
  publishToMaven: {
    javaPackage: 'com.cdk.hello',
    mavenArtifactId: 'cdk-construct-jsii',
    mavenGroupId: 'com.cdk.hello',
    mavenServerId: 'github',
    mavenRepositoryUrl: 'https://maven.pkg.github.com/example/hello-jsii',
  },
});

Run npx projen and the release.yml will be updated with Maven central details.

release_maven:
    name: Publish to Maven Central
    needs: release
    ....

Similarly, it can be published to other registries.

publishToPypi: 
publishToMaven:
publishToNuGet:
publishToGo:

This way the construct is built once and published to multiple registries with different programming languages.

Running Projen build runs a variety of processes.

Figure 1: High-level Architecture showing publication to multiple public registries

Linting, Dependency Management & Test Coverage

Projen streamlines the setup process by generating a comprehensive package.json file. This file includes pre-configured dependencies for ESLint and Jest, enabling developers to maintain coding standards and ensure robust test coverage right from the start. ESLint, a widely adopted static code analysis utility, empowers developers to enforce consistent coding practices by analyzing the source code and identifying potential errors, bugs, and stylistic issues. Additionally, Jest equips developers with a comprehensive suite of tools for writing and executing unit tests, facilitating comprehensive test coverage for their codebase. While Projen provides Jest as the default testing framework, it offers developers the flexibility to incorporate alternative testing frameworks based on their project requirements.

Following with the awscdk-construct from the previous section, under test>main.test.ts a default test file is created, which can be updated for writing test cases. A default package.json is generated in the root directory.

{
  "name": "projen_hello",
  "scripts": {
    "build": "npx projen build",
    "bundle": "npx projen bundle",
    "clobber": "npx projen clobber",
    "compile": "npx projen compile",
    "default": "npx projen default",
    "deploy": "npx projen deploy",
    "destroy": "npx projen destroy",
    "diff": "npx projen diff",
    "eject": "npx projen eject",
    "eslint": "npx projen eslint",
    "package": "npx projen package",
    "post-compile": "npx projen post-compile",
    "post-upgrade": "npx projen post-upgrade",
    "pre-compile": "npx projen pre-compile",
    "synth": "npx projen synth",
    "synth:silent": "npx projen synth:silent",
    "test": "npx projen test",
    "test:watch": "npx projen test:watch",
    "upgrade": "npx projen upgrade",
    "watch": "npx projen watch",
    "projen": "npx projen"
  },
  "devDependencies": {
    "@types/jest": "^29.5.4",
    "@types/node": "^16",
    "@typescript-eslint/eslint-plugin": "^6",
    "@typescript-eslint/parser": "^6",
    "aws-cdk": "^2.1.0",
    "esbuild": "^0.19.2",
    "eslint": "^8",
    "eslint-import-resolver-node": "^0.3.9",
    "eslint-import-resolver-typescript": "^3.6.0",
    "eslint-plugin-import": "^2.28.1",
    "jest": "^29.7.0",
    "jest-junit": "^15",
    "npm-check-updates": "^16",
    "projen": "^0.73.17",
    "ts-jest": "^29.1.1",
    "ts-node": "^10.9.1",
    "typescript": "^5.2.2",
    "webpack": "5.88.2"
  },
  "dependencies": {
    "aws-cdk-lib": "^2.1.0",
    "constructs": "^10.0.5"
  },
  "license": "Apache-2.0",
  "version": "0.0.0",
  "jest": {
    "testMatch": [
      "<rootDir>/src/**/__tests__/**/*.ts?(x)",
      "<rootDir>/(test|src)/**/*(*.)@(spec|test).ts?(x)"
    ],
    "clearMocks": true,
    "collectCoverage": true,
    "coverageReporters": [
      "json",
      "lcov",
      "clover",
      "cobertura",
      "text"
    ],
    "coverageDirectory": "coverage",
    "coveragePathIgnorePatterns": [
      "/node_modules/"
    ],
    "testPathIgnorePatterns": [
      "/node_modules/"
    ],
    "watchPathIgnorePatterns": [
      "/node_modules/"
    ],
    "reporters": [
      "default",
      [
        "jest-junit",
        {
          "outputDirectory": "test-reports"
        }
      ]
    ],
    "preset": "ts-jest",
    "globals": {
      "ts-jest": {
        "tsconfig": "tsconfig.dev.json"
      }
    }
  },
  "//": "~~ Generated by projen. To modify, edit .projenrc.ts and run \"npx projen\"."
}

Projen can be extensively configured. For example, if you need to configure webpack as a module bundler, then you need to add a webpack.config.js file and update the projenrc file project.

The other dependencies can be updated in package.json by adding deps in the projenrc.ts file.

const project = new awscdk.AwsCdkTypeScriptApp({
  cdkVersion: '2.1.0',
  defaultReleaseBranch: 'main',
  name: 'projen_hello',
  projenrcTs: true,
  
  deps:[
   "express",
  ],
  
  // add webpack dependencies
  devDeps:[
    "webpack",
    "webpack-cli",
    "ts-loader",
  ]
});
  
// update pre-configured build tasks and execute webpack
project.buildTask.reset
project.buildTask.exec('npx projen');
project.buildTask.exec('npx projen test');
project.buildTask.exec('npx webpack');

Run npx projen build to synthesize a package.json.

Continuous Integration and Continuous Delivery (CI/CD)

When you create a project using Projen, it comes equipped with an automated build process that triggers upon the submission of a pull request. This is one of the key, “out-of-the-box” features that streamlines development workflows.

Projen orchestrates this process through GitHub Actions, utilizing a sequence of tasks predefined in the project’s base ‘Project’ class.

When a build is initiated, it systematically carries out several sub-tasks:

  1. Synthesis: It starts by synthesizing all the project files, ensuring they are up-to-date and correctly configured.
  2. Bundling: Next, it bundles the necessary assets for the project.
  3. Compilation: The project’s code is then compiled.
  4. Testing: Following compilation, Projen runs the suite of tests defined for the project.
  5. Packaging: Finally, it packages everything together, preparing it for deployment or distribution.

Projen manages these steps by auto-generating a build.yml file, which it places within the workflow directory of your project’s structure. This YAML file contains all the instructions for the GitHub Actions to execute the build process.

For instance, when you run the command npx projen new awscdk-app-ts, Projen sets up a TypeScript application for AWS CDK. It automatically creates a ‘build.yml’ file through the default projenrc file, which can be found in the github/workflow folder of your project repository. This automated process is designed to save time and reduce manual errors, making it an essential feature for efficient project management.

 .github       
   workflow    
    build.yml  

A Projen build is self-mutating because files generated by Projen are part of the source directory. To ensure that a pull request branch always represents the final state of the repository, you can enable the mutableBuild option in your project configuration (currently only supported for projects derived from NodeProject).

The build process can be customized by adding any task in the project class, which can execute a shell command.

const buildproject = project.addTask('build'); 
buildproject.exec('npm run build');

You can spawn a subtask as well.

const buildproject = project.addTask('world');
buildproject.exec('echo world!');

const testproject = project.addTask('test');
testproject.exec('npm test');
testproject.spawn(buildproject);

The Task also supports the condition option that determines if the condition is true before running the task.

const hello = project.addTask('hello', {
  condition: '[ -n "$CI" ]', // only execute if the CI environment variable is defined
  exec: 'echo running in a CI environment'
});

Releases and Versioning

Projen uses Conventional Commits to generate semantic versioning of the releases automatically. This means that based on the commit message format, it can create the release version automatically.

Initially, the project is released under version 0.0.0. Anything may change at any time and public APIs should not be considered stable. Commits marked as a breaking change will increase the minor version. All other commits will increase the patch version.

You need to manually promote the major version to 1 once your project is considered stable. For major versions 1 and above, if a release includes fix commits only, it will increase the patch version. If a release includes any feat commits, then the new version will be a minor version.

Commit Messages                     Release versions         

feat: <Message>                     1.0.X (Patch)            
fix: <Message>                      1.X.0 (Minor)            
BREAKING CHANGE: <Message>          X.0 (Major)              

API Documentation

One of the nice, out-of-the-box features that comes with Projen for AWS CDK constructs is the creation of API documentation for your constructs. By leveraging jsii-docgen, Projen’s build step will generate API documentation (API.md) from the comments in your code.

This feature is powerful for several reasons. Firstly, it ensures that documentation is kept up-to-date with the codebase, as the API documentation is generated directly from the source code comments. This reduces the risk of discrepancies between the code and its documentation, which can lead to misunderstandings and errors in usage.

Secondly, it streamlines the development process by automating a task that is often tedious and time-consuming. Developers can focus more on writing code and less on updating documentation manually.

Thirdly, it promotes better coding practices, as developers are encouraged to write clear and detailed comments in their code. This not only benefits the generation of documentation, but also helps any new developers who may work on the codebase in the future to understand the code more quickly and thoroughly.

Moreover, having readily available and accurate documentation can significantly enhance the developer experience. It makes it more straightforward for users of the CDK constructs to understand the functionality, parameters, return types, and the structure of the code they are working with.

In the context of team collaboration and open-source projects, this feature is especially beneficial. It ensures that anyone who contributes to the codebase is able to generate and view the latest documentation without any additional setup or configuration, facilitating smoother collaboration and integration processes.

Let’s recap all of the features that Projen can introduce into your project right out of the box:

  1. Projen’s automation for linting and testing to maintain high code quality from the beginning.
  2. Automated API documentation feature to keep your project’s documentation synchronized with the latest code changes.
  3. Polyglot capabilities to cater to a diverse development team, ensuring flexibility in language preference.
  4. The publisher module to streamline the release process across multiple package managers, saving time and reducing the scope for human error.
  5. A list of awesome projects developed with Projen for inspiration or use as a template.

Conclusion

As we wrap up our deep dive into some of the advanced features of Projen within AWS CDK, it’s clear that Projen helps alleviate a lot of the pain points of a new greenfield project. By leveraging Projen, developers can navigate the complexities of polyglot programming, automate the mundane tasks of publishing and documentation, and ensure consistent code quality through linting and testing. Projen elevates the development workflow to a level where efficiency and scalability are the norms, not the exception.

What’s more compelling is Projen’s commitment to developer empowerment. Through its automated systems, it encourages developers to adhere to best practices without the overhead of manual enforcement. Its ability to seamlessly integrate with various package managers and generate detailed API documentation from inline comments signifies a leap in developer tooling.

Contact an AWS Representative to know how we can help accelerate your business.

Further Reading

Alain Krok image

Alain Krok

Alain Krok is a Senior Solutions Architect with a passion for emerging technologies. His past experience includes designing and implementing IoT solutions for the oil and gas industry and working on robotics projects. He enjoys pushing the limits and indulging in extreme sports when he is not designing software.

Dinesh Sajwan profile

Dinesh Sajwan

Dinesh Sajwan is a Senior Solutions Architect. His passion for emerging technologies allows him to stay on the cutting edge and identify new ways to apply the latest advancements to solve even the most complex business problems. His diverse expertise and enthusiasm for both technology and adventure position him as a uniquely creative problem-solver.

Michael Tran profile

Michael Tran

Michael Tran is a Senior Solutions Architect with Prototyping Acceleration team at Amazon Web Services. He provides technical guidance and helps customers innovate by showing the art of the possible on AWS. He specializes in building prototypes in the AI/ML space.

Accelerate application upgrades with Amazon Q Developer agent for code transformation

Post Syndicated from Jonathan Vogel original https://aws.amazon.com/blogs/devops/accelerate-application-upgrades-with-amazon-q-developer-agent-for-code-transformation/

In this blog, we will explore how Amazon Q Developer Agent for code transformation accelerates Java application upgrades. We will examine the benefits of this Generative AI-powered agent and outline strategies to achieve maximal acceleration, drawing from real-world success stories and best practices.

Benefits of using Amazon Q Developer to upgrade your applications

Amazon Q Developer addresses a critical challenge for organizations managing numerous Java applications, particularly as they face the approaching end of Long-Term-Support (LTS) for older Java versions. Upgrading to Java 17 enhances security, resolves vulnerabilities, and improves performance while ensuring long-term compatibility and access to modern features. Currently, Q Developer agent for code transformation supports upgrades from Java 8 and 11 to Java 17. Software developers can utilize Q Developer within their IDE (VS Code and JetBrains) to transform both single-module and multi-module applications. Q Developer will generate a plan that identifies necessary library upgrades and replacements for deprecated code in the application, proposing code changes with the goal of ensuring the transformed code compiles successfully in Java 17. Q Developer can significantly enhance the efficiency of your migration workflow, performing code transformations on applications in hours rather than weeks.

Customer success of using Q Developer to modernize legacy Java applications

Customers have used Q Developer to upgrade their Java applications successfully. Here is how two customers as well as Amazon internal teams use Q Developer to accelerate the migration process.

A large insurance company in North America strategically approached their Java upgrade initiative by identifying applications with dependencies that Q Developer could upgrade effectively. They focused on applications that rely on frameworks like Spring Boot, which can be time-consuming to upgrade manually. After leveraging Q Developer to transform 4 applications in pilot, they estimated a 36% acceleration in their upgrade process, indicating that Q Developer automatically completed over a third of the work that would have been required manually. While the remaining portion still necessitated manual intervention to ensure the code would build and run correctly, the effort acceleration was significant.

A major financial services firm’s experience with Q Developer proved equally compelling. In a focused two-day workshop, 20 developers successfully transformed 20 applications in production using the Amazon Q Developer agent. This results in 42% time savings using Q Developer compared to manual upgrade, saving on average 24 hours per application. They spent about 3 weeks to prepare for the transformation workshop. They identified first-party (1P) dependencies—internal libraries that other production applications rely on. Q developer does not guarantee upgrade of 1P dependencies. With a combination of Q Developer and manual work, the customer upgraded many of these common 1P dependencies leading up to the workshop. This step was crucial to gain maximum acceleration while using Q Developer for the upgrades.

Amazon uses Q Developer internally to upgrade Java applications following company-wide campaigns. The central team who owns the campaigns provides detailed guidance on which Java applications can be upgraded with Q developer most effectively. This team also manages Amazon’s internal build system and provides tooling to automate part of the manual efforts. They are able to achieve significant savings. Amazon was able to upgrade more than 50% of production applications in six months, 79% of the auto-generated code reviews were applied without additional changes.

Use Q Developer to upgrade your applications

To ensure that Q Developer is properly applied to the specific characteristics of their codebases, customers create and follow a transformation approach. Teams and individuals who understand the scope of the upgrade run campaigns across the company to effectively utilize Q Developer. To maximize the acceleration from Q Developer, these teams classify the applications which need to be upgraded, identify which ones can be upgraded using Q Developer, estimate the manual effort required, which provides a baseline to measure the value added by Q Developer agent for code transformation. The preparation phase is crucial before starting the execution phase of the upgrade. Each of the steps in the preparation phase plays an important role in maximizing the acceleration of Amazon Q in their upgrade processes.

  1. Classifying the applications to upgrade: Q Developer supports the upgrade of 30 most common Java libraries. Q Developer’s performance on less common and internal libraries is lower compared to the common libraries. In this case, you can use a combination of Q Developer and manual steps. It’s recommended to include both production applications and internal dependencies in this step. You should also classify your applications and internal libraries based on if/how they are used by other applications, it will help prioritize the applications to upgrade first in campaigns. Classifying applications by libraries used can help you identify the best upgrade approach using Q Developer.
  2. Defining baselines of efficiency: To measure the efficiency of the upgrade effort in your organization, it is crucial to establish baselines. Based on the classification of applications, use Q Developer in a pilot for each class to see which libraries are transformed correctly, and which ones have to be done manually. This helps you operationalize the process of using Q Developer and the manual steps required, and understand how this procedure accelerates the upgrade of a certain class of applications. Some customers use manual effort hours for each upgrade on dependency versions and deprecated code as baseline and compare the manual effort hours with time taken when completing the upgrade using Q Developer. For example, you can classify the applications based on the main frameworks used before upgrading applications using Q Developer. Compare the time taken by Q Developer with manual upgrade hours to understand which applications can be upgraded by Q Developer most effectively.
  3. Identifying applications for migration: Decide which applications to use Q Developer for, and prioritize the applications to upgrade in waves based on expected acceleration and business value. You can prioritize the applications which are most used by other applications and upgrade them in the initial campaign, then upgrade the rest of the applications in the subsequent campaigns. By addressing the foundational components first, the overall upgrade process will be streamlined. In Amazon, a centralized internal team defines migration waves and identifies which packages would be included in the upgrade campaign. Additionally, this team conducted analysis of the apps to determine the likelihood of the upgrade being successful using Q developer, and provides an estimate of the remaining engineering effort needed to complete the upgrade. The team will use this information to select applications and uses an Amazon-internal tool to assign the upgrade tasks to the team owning the applications. While SDEs were free to run the upgrade on their own, following the campaign with a set deadline mobilized the application owner teams to complete the upgrade.

Use Q Developer to automate upgrade tasks

Once the preparation phase is completed, you can start the execution phase. Software developers can use Q Developer to accelerate many of the steps in execution phase.

  1. Assessing the components of an application to upgrade. You can use Q Developer to start a transformation, at the beginning of the transformation, there will be a transformation plan generated for you to view which dependencies and deprecated code will be upgraded.
  2. Research and update dependency versions compatible to the target version. Q Developer will analyze your app and attempt to update the dependencies to the versions compatible with target Java version and in some cases the latest version.
  3. Replace deprecated methods and API calls which are not compatible to the target version. Q Developer will detect the deprecated code and attempt to update to what’s recommended in the compatible Java version.
  4. Reviewing the modified code and address any conflicts or issues that may arise. Q Developer will return code changes to you at the end of the transformation. If the transformation is successful, the app will compile in Java 17. If the transformation is partially successful, Q Developer was able to upgrade library versions and make code changes but could not compile the transformed app successfully in Java 17. Check out this part of our documentation on how to handle partial transformations.
  5. Test the upgraded application thoroughly to ensure correct functionality. Q Developer will run the unit tests and integration tests in your app when compiling in the target version.

Conclusion

As organizations face the pressing need to modernize their Java applications, Amazon Q Developer emerges as a powerful ally in this complex journey. The customer success stories demonstrate the tangible benefits of leveraging AI-assisted code transformation: significant time savings, reduced manual effort, and accelerated upgrade processes.

Q Developer not only addresses the technical challenges of Java upgrades, but also enables organizations to approach these initiatives strategically. By classifying applications, establishing baselines, and prioritizing upgrades, teams can maximize the efficiency of their modernization efforts. While Q Developer streamlines much of the upgrade process, it is important to note that some challenges may still arise. For a comprehensive understanding of potential challenges and detailed guidance on getting started with Q Developer, we encourage you to explore our public documentation.

The journey to Java 17 and beyond doesn’t have to be daunting. With Amazon Q Developer, you have a powerful tool at your disposal to accelerate your upgrade process, reduce costs, and ensure your applications remain secure, performant, and future-ready.

Take the first step towards modernizing your Java ecosystem today. Explore Amazon Q Developer and discover how it can transform your upgrade strategy. See Getting Started with Amazon Q Developer agent for code transformation for a how-to guide on using Q Developer to transform Java applications.

About the authors

Jonathan Vogel

Jonathan is a Developer Advocate at AWS. He was a DevOps Specialist Solutions Architect at AWS for two years prior to taking on the Developer Advocate role. Prior to AWS, he practiced professional software development for over a decade. Jonathan enjoys music, birding and climbing rocks.

Yiyi Guo

Yiyi is a Senior Product Manager at AWS working on Amazon Q developer agent for code transformation, she focuses on leveraging generative AI to accelerate enterprise application modernization.