Tag Archives: MySQL compatible

Extract data from Amazon Aurora MySQL to Amazon S3 Tables in Apache Iceberg format

Post Syndicated from Kunal Ghosh original https://aws.amazon.com/blogs/big-data/extract-data-from-amazon-aurora-mysql-to-amazon-s3-tables-in-apache-iceberg-format/

If you manage data in Amazon Aurora MySQL-Compatible Edition and want to make it available for analytics, machine learning (ML), or cross-service querying in a modern lakehouse format, you’re not alone.

Organizations often need to run analytics, build ML models, or join data across multiple sources. These are examples of workloads that can be resource-intensive and impractical to run directly against a transactional database. By extracting your Aurora MySQL data into Amazon S3 Tables in Apache Iceberg format, you can offload analytical queries from your production database without impacting its performance, while storing data in a fully managed Iceberg table store optimized for analytics. Built on the open Apache Iceberg standard, Amazon Simple Storage Service (Amazon S3) Table data is queryable from engines like Amazon Athena, Amazon Redshift Spectrum, and Apache Spark without additional data copies. You can also combine relational data with other datasets already in your data lake, enabling richer cross-domain insights.

Apache Iceberg and Amazon S3 Tables

Apache Iceberg is a widely adopted open table format that offers Atomicity, Consistency, Isolation, Durability (ACID) transactions, schema evolution, and time travel capabilities. It enables multiple engines to work concurrently on the same dataset, making it a popular choice for building open lakehouse architectures.

Amazon S3 Tables is a purpose-built, fully managed Apache Iceberg table store designed for analytics workloads. It delivers up to 3x faster query performance and up to 10x more transactions per second compared to self-managed Iceberg tables. It also automatically compacts data and removes unreferenced files to optimize storage and performance.

In this post, you learn how to set up an automated, end-to-end solution that extracts tables from Amazon Aurora MySQL Serverless v2 and writes them to Amazon S3 Tables in Apache Iceberg format using AWS Glue. The entire infrastructure is deployed using a single AWS CloudFormation stack.

Requirements

AWS offers zero-ETL integrations from Amazon Aurora to Amazon Redshift and Amazon SageMaker AI, enabling seamless data flow for analytics and machine learning workloads.

However, there isn’t yet a native zero-ETL integration between Amazon Aurora and Amazon S3 Tables. This means that organizations looking to use Amazon S3 Tables for their Lakehouse architecture currently face several requirements:

  • Setting up ETL pipelines to extract data from Amazon Aurora and transform it into Apache Iceberg format
  • Configuring networking and security for AWS Glue jobs to access Amazon Aurora databases in private subnets
  • Coordinating the provisioning of source databases, ETL pipelines, and target table stores
  • Managing the end-to-end workflow without native automation

Solution overview

In this solution, you automate the extraction of relational database tables from Amazon Aurora MySQL Serverless v2 to Amazon S3 Tables in Apache Iceberg format using AWS Glue 5.0. To help you get started and test this solution, a CloudFormation template is provided. This template provisions the required infrastructure, loads sample data, and configures the Extract, Transform, Load (ETL) pipeline. You can adapt this template for your own scenario.
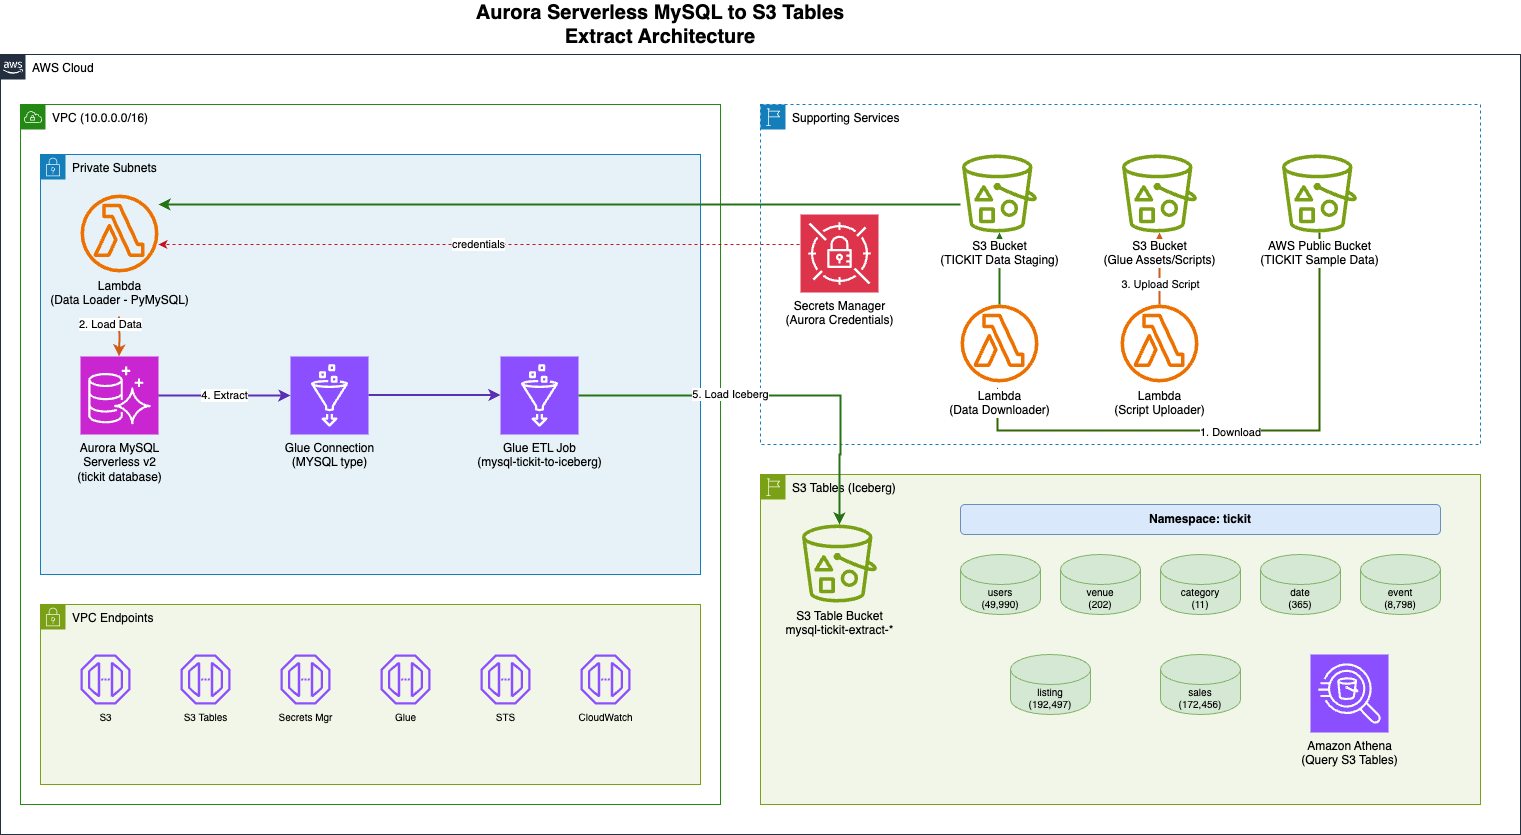
Solution overview

Sample data

This solution uses the TICKIT sample database, a well-known dataset used in Amazon Redshift documentation. The TICKIT data models a fictional ticket sales system with seven interrelated tables: users, venue, category, date, event, listing, and sales. The dataset is publicly available as mentioned in the Amazon Redshift Getting Started Guide.

Solution flow

The solution flow as shown in the previous architecture diagram:

  1. An AWS Lambda function downloads the TICKIT sample dataset (a fictional ticket sales system used in Amazon Redshift documentation) from a public Amazon S3 bucket to a staging S3 bucket.
  2. A second Lambda function, using PyMySQL (a Python MySQL client library), loads the staged data files into the Aurora MySQL Serverless v2 database using LOAD DATA LOCAL INFILE.
  3. The AWS Glue job reads seven TICKIT tables from Aurora MySQL through a native MySQL connection and writes them to Amazon S3 Tables in Apache Iceberg format using the S3 Tables REST catalog endpoint with SigV4 authentication.
  4. You can query the migrated data in S3 Tables using Amazon Athena.

The solution consists of the following key components:

  1. Amazon Aurora MySQL Serverless v2 as the source relational database containing the TICKIT sample dataset (users, venue, category, date, event, listing, and sales tables)
  2. AWS Secrets Manager to store the Aurora MySQL database credentials securely
  3. Amazon S3 staging bucket for the TICKIT sample data files downloaded from the public redshift-downloads S3 bucket
  4. AWS Lambda functions using PyMySQL to load data into Aurora MySQL
  5. AWS Glue 5.0 job (PySpark) to read tables from Aurora MySQL and write them to S3 Tables in Apache Iceberg format
  6. Amazon S3 Tables as the target storage for the migrated Iceberg tables
  7. Amazon VPC with private subnets and VPC endpoints for Amazon S3, S3 Tables, AWS Glue, Secrets Manager, AWS Security Token Service (AWS STS), CloudWatch Logs, and CloudFormation

Here are some advantages of this architecture:

  • Fully automated setup: A single CloudFormation stack provisions the required infrastructure, loads sample data, and configures the ETL pipeline.
  • Serverless and cost-efficient: Aurora MySQL Serverless v2 and AWS Glue both scale based on demand, minimizing idle costs.
  • Apache Iceberg table format: Data is stored in Apache Iceberg format, enabling ACID transactions, schema evolution, and time travel queries.
  • Network isolation and credential management: The resources run within private subnets with Virtual Private Cloud (VPC) endpoints, and database credentials are managed through AWS Secrets Manager.
  • Extensible pattern: The same approach can be adapted for other relational databases (PostgreSQL, SQL Server) and other target formats supported by AWS Glue.

Prerequisites

To follow along, you need an AWS account. If you don’t yet have an AWS account, you must create one. The CloudFormation stack deployment takes approximately 30-45 minutes to complete and requires familiarity with Amazon S3 Tables, AWS CloudFormation, Apache Iceberg, AWS Glue, Amazon Aurora. This solution will incur AWS costs. The main cost drivers are AWS Glue ETL job runs (billed per DPU-hour, proportional to data volume) and Amazon S3 Tables storage and request charges. Remember to clean up resources when you are done to avoid unnecessary charges.

CloudFormation parameters

You can configure the following parameters before deploying the CloudFormation stack:

Parameter Description Default Required
S3TableBucketName Name of the S3 Tables bucket to create (or use existing) Yes
DatabaseName Name of the initial Aurora MySQL database tickit No
MasterUsername Master username for Aurora MySQL admin No
VpcCidr CIDR block for the VPC 10.1.0.0/16 No
S3TableNamespace Namespace for S3 Tables tickit No

Implementation walkthrough

The following steps walk you through the implementation. These steps are to deploy and test an end-to-end solution from scratch. If you are already running some of these components, you may skip to the relevant step. You can also refer to the aws-samples repository, sample-to-write-aurora-mysql-to-s3tables-using-glue for the entire solution.

Step 1: Deploy the CloudFormation stack

Deploy the CloudFormation template scripts/aurora-mysql-to-s3tables-stack.yaml using the AWS Console or the AWS Command Line Interface (AWS CLI). Provide a name for the S3 Tables bucket; the stack will create it automatically (or use an existing one if it already exists).

To deploy using the AWS Console (recommended), navigate to the AWS CloudFormation Console and use the CloudFormation template. Alternatively, to deploy using the AWS CLI first upload the template to an S3 bucket (the template exceeds the 51,200 byte limit for inline –template-body), then create the stack.

# Upload the template to S3
aws s3 cp scripts/aurora-mysql-to-s3tables-stack.yaml \
  s3://<your-s3-bucket>/aurora-mysql-to-s3tables-stack.yaml \
  --region <your-region>
# Create the stack using the S3 template URL
aws cloudformation create-stack \
  --stack-name aurora-mysql-tickit-stack \
  --template-url https://<your-s3-bucket>.s3.<your-region>.amazonaws.com/aurora-mysql-to-s3tables-stack.yaml \
  --parameters \
    ParameterKey=S3TableBucketName,ParameterValue=<your-s3-table-bucket-name> \
  --capabilities CAPABILITY_NAMED_IAM \
  --region <your-region>

The stack will automatically:

  • Create the S3 Tables bucket (or use existing if it already exists)
  • Create a VPC with private subnets and VPC endpoints
  • Provision an Aurora MySQL Serverless v2 cluster
  • Download TICKIT sample data from the public Amazon S3 bucket
  • Load the sample data into Aurora MySQL via a Lambda function using PyMySQL
  • Create a Glue job configured to migrate data to S3 Tables in Iceberg format

Note: The S3 Tables bucket is retained when the stack is deleted to preserve your data.

Step 2: Verify the Aurora MySQL data

Retrieve the AuroraClusterEndpoint, DatabaseName, and SecretArn values from the CloudFormation stack, make a note of the AuroraClusterEndpoint, DatabaseName, and SecretArn. You can navigate to the Amazon Aurora Console, choose the Query Editor, and enter the values from the CloudFormation stack to connect. You can also choose your preferred method of connecting to an Amazon Aurora DB cluster.

Use the AWS CLI to retrieve the stack outputs: –

aws cloudformation describe-stacks --stack-name aurora-mysql-tickit-stack --region <your-region> --query "Stacks[0].Outputs"

Then run the following SQL commands to verify the data load:

-- Verify if the tables are created
SELECT * FROM information_schema.tables WHERE table_schema = 'tickit';

-- Verify if the data is loaded
SELECT 'users' AS table_name, COUNT(*) AS record_count FROM tickit.users
UNION ALL SELECT 'venue', COUNT(*) FROM tickit.venue
UNION ALL SELECT 'category', COUNT(*) FROM tickit.category
UNION ALL SELECT 'date', COUNT(*) FROM tickit.date
UNION ALL SELECT 'event', COUNT(*) FROM tickit.event
UNION ALL SELECT 'listing', COUNT(*) FROM tickit.listing
UNION ALL SELECT 'sales', COUNT(*) FROM tickit.sales;

Step 3: Run the Glue job

Navigate to the AWS Glue Console, choose ETL jobs under Data Integration and ETL from the left panel. Select the AWS Glue job mysql-tickit-to-iceberg-job and choose Run job to start execution. You can also start the ETL job using the AWS CLI:

aws glue start-job-run --job-name mysql-tickit-to-iceberg-job --region <your-region>

The AWS Glue job performs the following operations for each of the seven TICKIT tables:

  • Reads the table from Aurora MySQL through the native MYSQL Glue connection
  • Converts the data to a Spark DataFrame
  • Creates the Iceberg table in the S3 Tables namespace using CREATE TABLE IF NOT EXISTS with the USING ICEBERG clause
  • Inserts the data using INSERT INTO (or INSERT OVERWRITE if the table already exists)
  • Verifies the record count and displays sample data

Step 4: Verify the results

After the AWS Glue job completes, verify that the tables have been created in your S3 Table bucket by navigating to the Amazon S3 Console. Choose Table buckets under Buckets and select your S3 Table bucket. You can also verify using the AWS CLI:

aws s3tables list-tables \
  --table-bucket-arn arn:aws:s3tables:<your-region>:<your-account-id>:bucket/<your-s3-table-bucket-name> \
  --namespace tickit \
  --region <your-region>

Select a table from the tickit namespace and choose Preview to inspect the data.
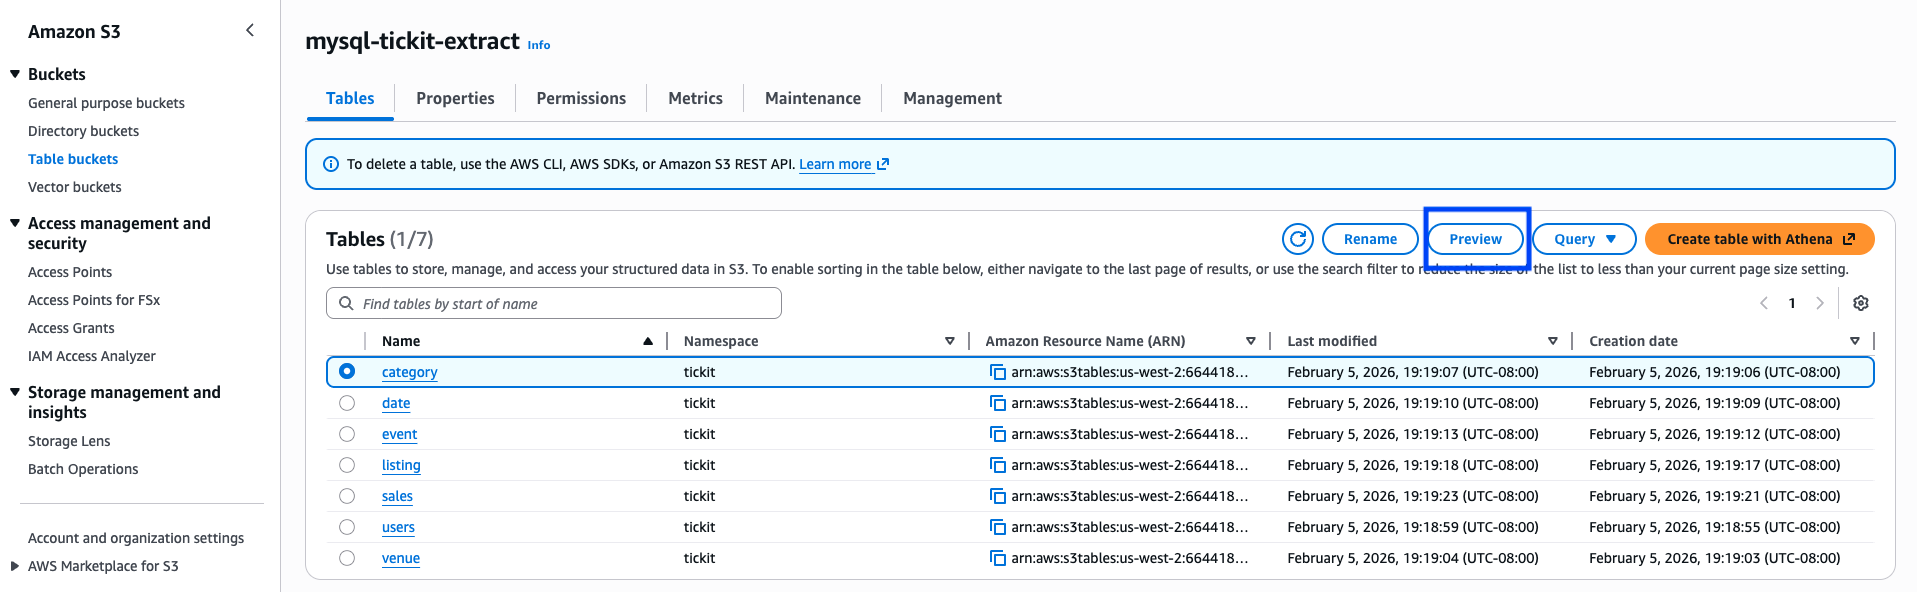
Preview S3 data

You can also query the migrated tables using Amazon Athena to validate the data.

Clean up resources

Remember to clean up resources when you no longer need them to avoid unnecessary charges.

Navigate to the CloudFormation console, search for your stack and choose Delete. Alternatively, use the AWS CLI:

aws cloudformation delete-stack --stack-name aurora-mysql-tickit-stack --region <your-region>

The S3 Tables bucket is retained by default. To delete it, use the Amazon S3 console or the AWS CLI to remove the table bucket separately. The staging S3 bucket will be automatically emptied and deleted as part of the stack deletion.

aws s3tables delete-table-bucket --table-bucket-arn arn:aws:s3tables:<your-region>:<your-account-id>:bucket/<your-s3-table-bucket-name> --region <your-region>

Summary

In this post, we showed you how to extract data from Amazon Aurora MySQL Serverless v2 and write it to Amazon S3 Tables in Apache Iceberg format using AWS Glue 5.0. By using the native Iceberg support of AWS Glue and the S3 Tables REST catalog endpoint, you can bridge the gap between relational databases and modern lakehouse storage formats. By automating the entire pipeline through CloudFormation, you can quickly set up and replicate this pattern across multiple environments.

As AWS Glue and Amazon S3 Tables continue to evolve, you can take advantage of future enhancements while maintaining this automated migration pattern.

If you have questions or suggestions, leave us a comment.


About the authors

Kunal Ghosh

Kunal Ghosh

Kunal is a Sr. Solutions Architect at AWS. He is passionate about building efficient and effective solutions on AWS, especially involving generative AI, analytics, data science, and machine learning. Besides family time, he likes reading, swimming, biking, and watching movies.

Arghya Banerjee

Arghya Banerjee

Arghya is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers adopt and use the AWS Cloud. He is focused on big data, data lakes, streaming and batch analytics services, and generative AI technologies.

Indranil Banerjee

Indranil Banerjee

Indranil is a Sr. Solutions Architect at AWS in the San Francisco Bay Area, focused on helping customers in the hi-tech and semi-conductor sectors solve complex business problems using the AWS Cloud. His special interests are in the areas of legacy modernization and migration, building analytics platforms and helping customers adopt cutting edge technologies such as generative AI.

Vipan Kumar

Vipan Kumar

Vipan is a Sr. Solutions Architect at AWS, where he works with strategic customers. He has extensive experience in machine learning and generative AI. With a background in application development, he is passionate about designing and building enterprise applications for the cloud.

Announcing data filtering for Amazon Aurora MySQL zero-ETL integration with Amazon Redshift

Post Syndicated from Jyoti Aggarwal original https://aws.amazon.com/blogs/big-data/announcing-data-filtering-for-amazon-aurora-mysql-zero-etl-integration-with-amazon-redshift/

As your organization becomes more data driven and uses data as a source of competitive advantage, you’ll want to run analytics on your data to better understand your core business drivers to grow sales, reduce costs, and optimize your business. To run analytics on your operational data, you might build a solution that is a combination of a database, a data warehouse, and an extract, transform, and load (ETL) pipeline. ETL is the process data engineers use to combine data from different sources.

To reduce the effort involved in building and maintaining ETL pipelines between transactional databases and data warehouses, AWS announced Amazon Aurora zero-ETL integration with Amazon Redshift at AWS re:Invent 2022 and is now generally available (GA) for Amazon Aurora MySQL-Compatible Edition 3.05.0.

AWS is now announcing data filtering on zero-ETL integrations, enabling you to bring in selective data from the database instance on zero-ETL integrations between Amazon Aurora MySQL and Amazon Redshift. This feature allows you to select individual databases and tables to be replicated to your Redshift data warehouse for analytics use cases.

In this post, we provide an overview of use cases where you can use this feature, and provide step-by-step guidance on how to get started with near real time operational analytics using this feature.

Data filtering use cases

Data filtering allows you to choose the databases and tables to be replicated from Amazon Aurora MySQL to Amazon Redshift. You can apply multiple filters to the zero-ETL integration, allowing you to tailor the replication to your specific needs. Data filtering applies either an exclude or include filter rule, and can use regular expressions to match multiple databases and tables.

In this section, we discuss some common use cases for data filtering.

Improve data security by excluding tables containing PII data from replication

Operational databases often contain personally identifiable information (PII). This is information that is sensitive in nature, and can include information such as mailing addresses, customer verification documentation, or credit card information.

Due to strict security compliance regulations, you may not want to use PII for your analytics use cases. Data filtering allows you to filter out databases or tables containing PII data, excluding them from replication to Amazon Redshift. This improves data security and compliance with analytics workloads.

Save on storage costs and manage analytics workloads by replicating tables required for specific use cases

Operational databases often contain many different datasets that aren’t useful for analytics. This includes supplementary data, specific application data, and multiple copies of the same dataset for different applications.

Moreover, it’s common to build different use cases on different Redshift warehouses. This architecture requires different datasets to be available in individual endpoints.

Data filtering allows you to only replicate the datasets that are required for your use cases. This can save costs by eliminating the need to store data that is not being used.

You can also modify existing zero-ETL integrations to apply more restrictive data replication where desired. If you add a data filter to an existing integration, Aurora will fully reevaluate the data being replicated with the new filter. This will remove the newly filtered data from the target Redshift endpoint.

For more information about quotas for Aurora zero-ETL integrations with Amazon Redshift, refer to Quotas.

Start with small data replication and incrementally add tables as required

As more analytics use cases are developed on Amazon Redshift, you may want to add more tables to an individual zero-ETL replication. Rather than replicating all tables to Amazon Redshift to satisfy the chance that they may be used in the future, data filtering allows you to start small with a subset of tables from your Aurora database and incrementally add more tables to the filter as they’re required.

After a data filter on a zero-ETL integration is updated, Aurora will fully reevaluate the entire filter as if the previous filter didn’t exist, so workloads using previously replicated tables aren’t impacted in the addition of new tables.

Improve individual workload performance by load balancing replication processes

For large transactional databases, you may need to load balance the replication and any downstream processing to multiple Redshift clusters to allow for reduction of compute requirements for an individual Redshift endpoint and the ability to split workloads onto multiple endpoints. By load balancing workloads across multiple Redshift endpoints, you can effectively create a data mesh architecture, where endpoints are appropriately sized for individual workloads. This can improve performance and lower overall cost.

Data filtering allows you to replicate different databases and tables to separate Redshift endpoints.

The following figure shows how you could use data filters on zero-ETL integrations to split different databases in Aurora to separate Redshift endpoints.

Example use case

Consider the TICKIT database. The TICKIT sample database contains data from a fictional company where users can buy and sell tickets for various events. The company’s business analysts want to use the data that is stored in their Aurora MySQL database to generate various metrics, and would like to perform this analysis in near real time. For this reason, the company has identified zero-ETL as a potential solution.

Throughout their investigation of the datasets required, the company’s analysts noted that the users table contains personal information about their customer user information that is not useful for their analytics requirements. Therefore, they want to replicate all data except the users table and will use zero-ETL’s data filtering to do so.

Setup

Start by following the steps in Getting started guide for near-real time operational analytics using Amazon Aurora zero-ETL integration with Amazon Redshift to create a new Aurora MySQL database, Amazon Redshift Serverless endpoint, and zero-ETL integration. Then open the Redshift query editor v2 and run the following query to show that data from the users table has been replicated successfully:

select * from aurora_zeroetl.demodb.users;

Data filters

Data filters are applied directly to the zero-ETL integration on Amazon Relational Database Service (Amazon RDS). You can define multiple filters for a single integration, and each filter is defined as either an Include or Exclude filter type. Data filters apply a pattern to existing and future database tables to determine which filter should be applied.

Apply a data filter

To apply a filter to remove the users table from the zero-ETL integration, complete the following steps:

  1. On the Amazon RDS console, choose Zero-ETL integrations in the navigation pane.
  2. Choose the zero-ETL integration to add a filter to.

The default filter is to include all databases and tables represented by an include:*.* filter.

  1. Choose Modify.
  2. Choose Add filter in the Source section.
  3. For Choose filter type, choose Exclude.
  4. For Filter expression, enter the expression demodb.users.

Filter expression order matters. Filters are evaluated left to right, top to bottom, and subsequent filters will override previous filters. In this example, Aurora will evaluate that every table should be included (filter 1) and then evaluate that the demodb.users table should be excluded (filter 2). The exclusion filter therefore overrides the inclusion because it’s after the inclusion filter.

  1. Choose Continue.
  2. Review the changes, making sure that the order of the filters is correct, and choose Save changes.

The integration will be added and will be in a Modifying state until the changes have been applied. This can take up to 30 minutes. To check if the changes have finished applying, choose the zero-ETL integration and check its status. When it shows as Active, the changes have been applied.

Verify the change

To verify the zero-ETL integration has been updated, complete the following steps:

  1. In the Redshift query editor v2, connect to your Redshift cluster.
  2. Choose (right-click) the aurora-zeroetl database you created and choose Refresh.
  3. Expand demodb and Tables.

The users table is no longer available because it has been removed from the replication. All other tables are still available.

  1. If you run the same SELECT statement from earlier, you will receive an error stating the object does not exist in the database:
    select * from aurora_zeroetl.demodb.users;

Apply a data filter using the AWS CLI

The company’s business analysts now understand that more databases are being added to the Aurora MySQL database and they want to ensure only the demodb database is replicated to their Redshift cluster. To this end, they want to update the filters on the zero-ETL integration with the AWS Command Line Interface (AWS CLI).

To add data filters to a zero-ETL integration using the AWS CLI, you can call the modify-integration command. In addition to the integration identifier, specify the --data-filter parameter with a comma-separated list of include and exclude filters.

Complete the following steps to alter the filter on the zero-ETL integration:

  1. Open a terminal with the AWS CLI installed.
  2. Enter the following command to list all available integrations:
    aws rds describe-integrations

  3. Find the integration you want to update and copy the integration identifier.

The integration identifier is an alphanumeric string at the end of the integration ARN.

  1. Run the following command, updating <integration identifier> with the identifier copied from the previous step:
    aws rds modify-integration --integration-identifier "<integration identifier>" --data-filter 'exclude: *.*, include: demodb.*, exclude: demodb.users'

When Aurora is assessing this filter, it will exclude everything by default, then only include the demodb database, but exclude the demodb.users table.

Data filters can implement regular expressions for the databases and table. For example, if you want to filter out any tables starting with user, you can run the following:

aws rds modify-integration --integration-identifier "<integration identifier>" --data-filter 'exclude: *.*, include: demodb.*, exclude *./^user/'

As with the previous filter change, the integration will be added and will be in a Modifying state until the changes have been applied. This can take up to 30 minutes. When it shows as Active, the changes have been applied.

Clean up

To remove the filter added to the zero-ETL integration, complete the following steps:

  1. On the Amazon RDS console, choose Zero-ETL integrations in the navigation pane.
  2. Choose your zero-ETL integration.
  3. Choose Modify.
  4. Choose Remove next to the filters you want to remove.
  5. You can also change the Exclude filter type to Include.

Alternatively, you can use the AWS CLI to run the following:

aws rds modify-integration --integration-identifier "<integration identifier>" --data-filter 'include: *.*'
  1. Choose Continue.
  2. Choose Save changes.

The data filter will take up to 30 minutes to apply the changes. After you remove data filters, Aurora reevaluates the remaining filters as if the removed filter had never existed. Any data that previously didn’t match the filtering criteria but now does is replicated into the target Redshift data warehouse.

Conclusion

In this post, we showed you how to set up data filtering on your Aurora zero-ETL integration from Amazon Aurora MySQL to Amazon Redshift. This allows you to enable near real time analytics on transactional and operational data while replicating only the data required.

With data filtering, you can split workloads into separate Redshift endpoints, limit the replication of private or confidential datasets, and increase performance of workloads by only replicating required datasets.

To learn more about Aurora zero-ETL integration with Amazon Redshift, see Working with Aurora zero-ETL integrations with Amazon Redshift and Working with zero-ETL integrations.


About the authors

Jyoti Aggarwal is a Product Management Lead for AWS zero-ETL. She leads the product and business strategy, including driving initiatives around performance, customer experience, and security. She brings along an expertise in cloud compute, data pipelines, analytics, artificial intelligence (AI), and data services including databases, data warehouses and data lakes.


Sean Beath
is an Analytics Solutions Architect at Amazon Web Services. He has experience in the full delivery lifecycle of data platform modernisation using AWS services, and works with customers to help drive analytics value on AWS.

Gokul Soundararajan is a principal engineer at AWS and received a PhD from University of Toronto and has been working in the areas of storage, databases, and analytics.

Your MySQL 5.7 and PostgreSQL 11 databases will be automatically enrolled into Amazon RDS Extended Support

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/your-mysql-5-7-and-postgresql-11-databases-will-be-automatically-enrolled-into-amazon-rds-extended-support/

Today, we are announcing that your MySQL 5.7 and PostgreSQL 11 database instances running on Amazon Aurora and Amazon Relational Database Service (Amazon RDS) will be automatically enrolled into Amazon RDS Extended Support starting on February 29, 2024.

This will help avoid unplanned downtime and compatibility issues that can arise with automatically upgrading to a new major version. This provides you with more control over when you want to upgrade the major version of your database.

This automatic enrollment may mean that you will experience higher charges when RDS Extended Support begins. You can avoid these charges by upgrading your database to a newer DB version before the start of RDS Extended Support.

What is Amazon RDS Extended Support?
In September 2023, we announced Amazon RDS Extended Support, which allows you to continue running your database on a major engine version past its RDS end of standard support date on Amazon Aurora or Amazon RDS at an additional cost.

Until community end of life (EoL), the MySQL and PostgreSQL open source communities manage common vulnerabilities and exposures (CVE) identification, patch generation, and bug fixes for the respective engines. The communities release a new minor version every quarter containing these security patches and bug fixes until the database major version reaches community end of life. After the community end of life date, CVE patches or bug fixes are no longer available and the community considers those engines unsupported. For example, MySQL 5.7 and PostgreSQL 11 are no longer supported by the communities as of October and November 2023 respectively. We are grateful to the communities for their continued support of these major versions and a transparent process and timeline for transitioning to the newest major version.

With RDS Extended Support, Amazon Aurora and RDS takes on engineering the critical CVE patches and bug fixes for up to three years beyond a major version’s community EoL. For those 3 years, Amazon Aurora and RDS will work to identify CVEs and bugs in the engine, generate patches and release them to you as quickly as possible. Under RDS Extended Support, we will continue to offer support, such that the open source community’s end of support for an engine’s major version does not leave your applications exposed to critical security vulnerabilities or unresolved bugs.

You might wonder why we are charging for RDS Extended Support rather than providing it as part of the RDS service. It’s because the engineering work for maintaining security and functionality of community EoL engines requires AWS to invest developer resources for critical CVE patches and bug fixes. This is why RDS Extended Support is only charging customers who need the additional flexibility to stay on a version past community EoL.

RDS Extended Support may be useful to help you meet your business requirements for your applications if you have particular dependencies on a specific MySQL or PostgreSQL major version, such as compatibility with certain plugins or custom features. If you are currently running on-premises database servers or self-managed Amazon Elastic Compute Cloud (Amazon EC2) instances, you can migrate to Amazon Aurora MySQL-Compatible Edition, Amazon Aurora PostgreSQL-Compatible Edition, Amazon RDS for MySQL, Amazon RDS for PostgreSQL beyond the community EoL date, and continue to use these versions these versions with RDS Extended Support while benefiting from a managed service. If you need to migrate many databases, you can also utilize RDS Extended Support to split your migration into phases, ensuring a smooth transition without overwhelming IT resources.

In 2024, RDS Extended Support will be available for RDS for MySQL major versions 5.7 and higher, RDS for PostgreSQL major versions 11 and higher, Aurora MySQL-compatible version 2 and higher, and Aurora PostgreSQL-compatible version 11 and higher. For a list of all future supported versions, see Supported MySQL major versions on Amazon RDS and Amazon Aurora major versions in the AWS documentation.

Community major version RDS/Aurora version Community end of life date End of RDS standard support date Start of RDS Extended Support pricing End of RDS Extended Support
MySQL 5.7 RDS for MySQL 5.7 October 2023 February 29, 2024 March 1, 2024 February 28, 2027
Aurora MySQL 2 October 31, 2024 December 1, 2024
PostgreSQL 11 RDS for PostgreSQL 11 November 2023 March 31, 2024 April 1, 2024 March 31, 2027
Aurora PostgreSQL 11 February 29, 2024

RDS Extended Support is priced per vCPU per hour. Learn more about pricing details and timelines for RDS Extended Support at Amazon Aurora pricing, RDS for MySQL pricing, and RDS for PostgreSQL pricing. For more information, see the blog posts about Amazon RDS Extended Support for MySQL and PostgreSQL databases in the AWS Database Blog.

Why are we automatically enrolling all databases to Amazon RDS Extended Support?
We had originally informed you that RDS Extended Support would provide the opt-in APIs and console features in December 2023. In that announcement, we said that if you decided not to opt your database in to RDS Extended Support, it would automatically upgrade to a newer engine version starting on March 1, 2024. For example, you would be upgraded from Aurora MySQL 2 or RDS for MySQL 5.7 to Aurora MySQL 3 or RDS for MySQL 8.0 and from Aurora PostgreSQL 11 or RDS for PostgreSQL 11 to Aurora PostgreSQL 15 and RDS for PostgreSQL 15, respectively.

However, we heard lots of feedback from customers that these automatic upgrades may cause their applications to experience breaking changes and other unpredictable behavior between major versions of community DB engines. For example, an unplanned major version upgrade could introduce compatibility issues or downtime if applications are not ready for MySQL 8.0 or PostgreSQL 15.

Automatic enrollment in RDS Extended Support gives you additional time and more control to organize, plan, and test your database upgrades on your own timeline, providing you flexibility on when to transition to new major versions while continuing to receive critical security and bug fixes from AWS.

If you’re worried about increased costs due to automatic enrollment in RDS Extended Support, you can avoid RDS Extended Support and associated charges by upgrading before the end of RDS standard support.

How to upgrade your database to avoid RDS Extended Support charges
Although RDS Extended Support helps you schedule your upgrade on your own timeline, sticking with older versions indefinitely means missing out on the best price-performance for your database workload and incurring additional costs from RDS Extended Support.

MySQL 8.0 on Aurora MySQL, also known as Aurora MySQL 3, unlocks support for popular Aurora features, such as Global Database, Amazon RDS Proxy, Performance Insights, Parallel Query, and Serverless v2 deployments. Upgrading to RDS for MySQL 8.0 provides features including up to three times higher performance versus MySQL 5.7, such as Multi-AZ cluster deployments, Optimized Reads, Optimized Writes, and support for AWS Graviton2 and Graviton3-based instances.

PostgreSQL 15 on Aurora PostgreSQL supports the Aurora I/O Optimized configuration, Aurora Serverless v2, Babelfish for Aurora PostgreSQL, pgvector extension, Trusted Language Extensions for PostgreSQL (TLE), and AWS Graviton3-based instances as well as community enhancements. Upgrading to RDS for PostgreSQL 15 provides features such as Multi-AZ DB cluster deployments, RDS Optimized Reads, HypoPG extension, pgvector extension, TLEs for PostgreSQL, and AWS Graviton3-based instances.

Major version upgrades may make database changes that are not backward-compatible with existing applications. You should manually modify your database instance to upgrade to the major version. It is strongly recommended that you thoroughly test any major version upgrade on non-production instances before applying it to production to ensure compatibility with your applications. For more information about an in-place upgrade from MySQL 5.7 to 8.0, see the incompatibilities between the two versions, Aurora MySQL in-place major version upgrade, and RDS for MySQL upgrades in the AWS documentation. For the in-place upgrade from PostgreSQL 11 to 15, you can use the pg_upgrade method.

To minimize downtime during upgrades, we recommend using Fully Managed Blue/Green Deployments in Amazon Aurora and Amazon RDS. With just a few steps, you can use Amazon RDS Blue/Green Deployments to create a separate, synchronized, fully managed staging environment that mirrors the production environment. This involves launching a parallel green environment with upper version replicas of your production databases lower version. After validating the green environment, you can shift traffic over to it. Then, the blue environment can be decommissioned. To learn more, see Blue/Green Deployments for Aurora MySQL and Aurora PostgreSQL or Blue/Green Deployments for RDS for MySQL and RDS for PostgreSQL in the AWS documentation. In most cases, Blue/Green Deployments are the best option to reduce downtime, except for limited cases in Amazon Aurora or Amazon RDS.

For more information on performing a major version upgrade in each DB engine, see the following guides in the AWS documentation.

Now available
Amazon RDS Extended Support is now available for all customers running Amazon Aurora and Amazon RDS instances using MySQL 5.7, PostgreSQL 11, and higher major versions in AWS Regions, including the AWS GovCloud (US) Regions beyond the end of the standard support date in 2024. You don’t need to opt in to RDS Extended Support, and you get the flexibility to upgrade your databases and continued support for up to 3 years.

Learn more about RDS Extended Support in the Amazon Aurora User Guide and the Amazon RDS User Guide. For pricing details and timelines for RDS Extended Support, see Amazon Aurora pricing, RDS for MySQL pricing, and RDS for PostgreSQL pricing.

Please send feedback to AWS re:Post for Amazon RDS and Amazon Aurora or through your usual AWS Support contacts.

Channy

New for AWS Amplify – Query MySQL and PostgreSQL database for AWS CDK

Post Syndicated from Channy Yun original https://aws.amazon.com/blogs/aws/new-for-aws-amplify-query-mysql-and-postgresql-database-for-aws-cdk/

Today we are announcing the general availability to connect and query your existing MySQL and PostgreSQL databases with support for AWS Cloud Development Kit (AWS CDK), a new feature to create a real-time, secure GraphQL API for your relational database within or outside Amazon Web Services (AWS). You can now generate the entire API for all relational database operations with just your database endpoint and credentials. When your database schema changes, you can run a command to apply the latest table schema changes.

In 2021, we announced AWS Amplify GraphQL Transformer version 2, enabling developers to develop more feature-rich, flexible, and extensible GraphQL-based app backends even with minimal cloud expertise. This new GraphQL Transformer was redesigned from the ground up to generate extensible pipeline resolvers to route a GraphQL API request, apply business logic, such as authorization, and communicate with the underlying data source, such as Amazon DynamoDB.

However, customers wanted to use relational database sources for their GraphQL APIs such as their Amazon RDS or Amazon Aurora databases in addition to Amazon DynamoDB. You can now use @model types of Amplify GraphQL APIs for both relational database and DynamoDB data sources. Relational database information is generated to a separate schema.sql.graphql file. You can continue to use the regular schema.graphql files to create and manage DynamoDB-backed types.

When you simply provide any MySQL or PostgreSQL database information, whether behind a virtual private cloud (VPC) or publicly accessible on the internet, AWS Amplify automatically generates a modifiable GraphQL API that securely connects to your database tables and exposes create, read, update, or delete (CRUD) queries and mutations. You can also rename your data models to be more idiomatic for the frontend. For example, a database table is called “todos” (plural, lowercase) but is exposed as “ToDo” (singular, PascalCase) to the client.

With one line of code, you can add any of the existing Amplify GraphQL authorization rules to your API, making it seamless to build use cases such as owner-based authorization or public read-only patterns. Because the generated API is built on AWS AppSync‘ GraphQL capabilities, secure real-time subscriptions are available out of the box. You can subscribe to any CRUD events from any data model with a few lines of code.

Getting started with your MySQL database in AWS CDK
The AWS CDK lets you build reliable, scalable, cost-effective applications in the cloud with the considerable expressive power of a programming language. To get started, install the AWS CDK on your local machine.

$ npm install -g aws-cdk

Run the following command to verify the installation is correct and print the version number of the AWS CDK.

$ cdk –version

Next, create a new directory for your app:

$ mkdir amplify-api-cdk
$ cd amplify-api-cdk

Initialize a CDK app by using the cdk init command.

$ cdk init app --language typescript

Install Amplify’s GraphQL API construct in the new CDK project:

$ npm install @aws-amplify/graphql-api-construct

Open the main stack file in your CDK project (usually located in lib/<your-project-name>-stack.ts). Import the necessary constructs at the top of the file:

import {
    AmplifyGraphqlApi,
    AmplifyGraphqlDefinition
} from '@aws-amplify/graphql-api-construct';

Generate a GraphQL schema for a new relational database API by executing the following SQL statement on your MySQL database. Make sure to output the results to a .csv file, including column headers, and replace <database-name> with the name of your database, schema, or both.

SELECT
  INFORMATION_SCHEMA.COLUMNS.TABLE_NAME,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_NAME,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_DEFAULT,
  INFORMATION_SCHEMA.COLUMNS.ORDINAL_POSITION,
  INFORMATION_SCHEMA.COLUMNS.DATA_TYPE,
  INFORMATION_SCHEMA.COLUMNS.COLUMN_TYPE,
  INFORMATION_SCHEMA.COLUMNS.IS_NULLABLE,
  INFORMATION_SCHEMA.COLUMNS.CHARACTER_MAXIMUM_LENGTH,
  INFORMATION_SCHEMA.STATISTICS.INDEX_NAME,
  INFORMATION_SCHEMA.STATISTICS.NON_UNIQUE,
  INFORMATION_SCHEMA.STATISTICS.SEQ_IN_INDEX,
  INFORMATION_SCHEMA.STATISTICS.NULLABLE
      FROM INFORMATION_SCHEMA.COLUMNS
      LEFT JOIN INFORMATION_SCHEMA.STATISTICS ON INFORMATION_SCHEMA.COLUMNS.TABLE_NAME=INFORMATION_SCHEMA.STATISTICS.TABLE_NAME AND INFORMATION_SCHEMA.COLUMNS.COLUMN_NAME=INFORMATION_SCHEMA.STATISTICS.COLUMN_NAME
      WHERE INFORMATION_SCHEMA.COLUMNS.TABLE_SCHEMA = '<database-name>';

Run the following command, replacing <path-schema.csv> with the path to the .csv file created in the previous step.

$ npx @aws-amplify/cli api generate-schema \
    --sql-schema <path-to-schema.csv> \
    --engine-type mysql –out lib/schema.sql.graphql

You can open schema.sql.graphql file to see the imported data model from your MySQL database schema.

input AMPLIFY {
     engine: String = "mysql"
     globalAuthRule: AuthRule = {allow: public}
}

type Meals @model {
     id: Int! @primaryKey
     name: String!
}

type Restaurants @model {
     restaurant_id: Int! @primaryKey
     address: String!
     city: String!
     name: String!
     phone_number: String!
     postal_code: String!
     ...
}

If you haven’t already done so, go to the Parameter Store in the AWS Systems Manager console and create a parameter for the connection details of your database, such as hostname/url, database name, port, username, and password. These will be required in the next step for Amplify to successfully connect to your database and perform GraphQL queries or mutations against it.

In the main stack class, add the following code to define a new GraphQL API. Replace the dbConnectionConfg options with the parameter paths created in the previous step.

new AmplifyGraphqlApi(this, "MyAmplifyGraphQLApi", {
  apiName: "MySQLApi",
  definition: AmplifyGraphqlDefinition.fromFilesAndStrategy(
    [path.join(__dirname, "schema.sql.graphql")],
    {
      name: "MyAmplifyGraphQLSchema",
      dbType: "MYSQL",
      dbConnectionConfig: {
        hostnameSsmPath: "/amplify-cdk-app/hostname",
        portSsmPath: "/amplify-cdk-app/port",
        databaseNameSsmPath: "/amplify-cdk-app/database",
        usernameSsmPath: "/amplify-cdk-app/username",
        passwordSsmPath: "/amplify-cdk-app/password",
      },
    }
  ),
  authorizationModes: { apiKeyConfig: { expires: cdk.Duration.days(7) } },
  translationBehavior: { sandboxModeEnabled: true },
});

This configuration assums that your database is accessible from the internet. Also, the default authorization mode is set to Api Key for AWS AppSync and the sandbox mode is enabled to allow public access on all models. This is useful for testing your API before adding more fine-grained authorization rules.

Finally, deploy your GraphQL API to AWS Cloud.

$ cdk deploy

You can now go to the AWS AppSync console and find your created GraphQL API.

Choose your project and the Queries menu. You can see newly created GraphQL APIs compatible with your tables of MySQL database, such as getMeals to get one item or listRestaurants to list all items.

For example, when you select items with fields of address, city, name, phone_number, and so on, you can see a new GraphQL query. Choose the Run button and you can see the query results from your MySQL database.

When you query your MySQL database, you can see the same results.

How to customize your GraphQL schema for your database
To add a custom query or mutation in your SQL, open the generated schema.sql.graphql file and use the @sql(statement: "") pass in parameters using the :<variable> notation.

type Query {
     listRestaurantsInState(state: String): Restaurants @sql("SELECT * FROM Restaurants WHERE state = :state;”)
}

For longer, more complex SQL queries, you can reference SQL statements in the customSqlStatements config option. The reference value must match the name of a property mapped to a SQL statement. In the following example, a searchPosts property on customSqlStatements is being referenced:

type Query {
      searchPosts(searchTerm: String): [Post]
      @sql(reference: "searchPosts")
}

Here is how the SQL statement is mapped in the API definition.

new AmplifyGraphqlApi(this, "MyAmplifyGraphQLApi", { 
    apiName: "MySQLApi",
    definition: AmplifyGraphqlDefinition.fromFilesAndStrategy( [path.join(__dirname, "schema.sql.graphql")],
    {
        name: "MyAmplifyGraphQLSchema",
        dbType: "MYSQL",
        dbConnectionConfig: {
        //	...ssmPaths,
     }, customSqlStatements: {
        searchPosts: // property name matches the reference value in schema.sql.graphql 
        "SELECT * FROM posts WHERE content LIKE CONCAT('%', :searchTerm, '%');",
     },
    }
  ),
//...
});

The SQL statement will be executed as if it were defined inline in the schema. The same rules apply in terms of using parameters, ensuring valid SQL syntax, and matching return types. Using a reference file keeps your schema clean and allows the reuse of SQL statements across fields. It is best practice for longer, more complicated SQL queries.

Or you can change a field and model name using the @refersTo directive. If you don’t provide the @refersTo directive, AWS Amplify assumes that the model name and field name exactly match the database table and column names.

type Todo @model @refersTo(name: "todos") {
     content: String
     done: Boolean
}

When you want to create relationships between two database tables, use the @hasOne and @hasMany directives to establish a 1:1 or 1:M relationship. Use the @belongsTo directive to create a bidirectional relationship back to the relationship parent. For example, you can make a 1:M relationship between a restaurant and its meals menus.

type Meals @model {
     id: Int! @primaryKey
     name: String!
     menus: [Restaurants] @hasMany(references: ["restaurant_id"])
}

type Restaurants @model {
     restaurant_id: Int! @primaryKey
     address: String!
     city: String!
     name: String!
     phone_number: String!
     postal_code: String!
     meals: Meals @belongsTo(references: ["restaurant_id"])
     ...
}

Whenever you make any change to your GraphQL schema or database schema in your DB instances, you should deploy your changes to the cloud:

Whenever you make any change to your GraphQL schema or database schema in your DB instances, you should re-run the SQL script and export to .csv step mentioned earlier in this guide to re-generate your schema.sql.graphql file and then deploy your changes to the cloud:

$ cdk deploy

To learn more, see Connect API to existing MySQL or PostgreSQL database in the AWS Amplify documentation.

Now available
The relational database support for AWS Amplify now works with any MySQL and PostgreSQL databases hosted anywhere within Amazon VPC or even outside of AWS Cloud.

Give it a try and send feedback to AWS re:Post for AWS Amplify, the GitHub repository of Amplify GraphQL API, or through your usual AWS Support contacts.

Channy

P.S. Specially thanks to René Huangtian Brandel, a principal product manager at AWS for his contribution to write sample codes.