How AWS tracks the cloud’s biggest security threats and helps shut them down

Post Syndicated from CJ Moses original https://aws.amazon.com/blogs/security/how-aws-tracks-the-clouds-biggest-security-threats-and-helps-shut-them-down/

Threat intelligence that can fend off security threats before they happen requires not just smarts, but the speed and worldwide scale that only AWS can offer.

Organizations around the world trust Amazon Web Services (AWS) with their most sensitive data. One of the ways we help secure data on AWS is with an industry-leading threat intelligence program where we identify and stop many kinds of malicious online activities that could harm or disrupt our customers or our infrastructure. Producing accurate, timely, actionable, and scalable threat intelligence is a responsibility we take very seriously, and is something we invest significant resources in.

Customers increasingly ask us where our threat intelligence comes from, what types of threats we see, how we act on what we observe, and what they need to do to protect themselves. Questions like these indicate that Chief Information Security Officers (CISOs)—whose roles have evolved from being primarily technical to now being a strategic, business-oriented function—understand that effective threat intelligence is critical to their organizations’ success and resilience. This blog post is the first of a series that begins to answer these questions and provides examples of how AWS threat intelligence protects our customers, partners, and other organizations.

High-fidelity threat intelligence that can only be achieved at the global scale of AWS

Every day across AWS infrastructure, we detect and thwart cyberattacks. With the largest public network footprint of any cloud provider, AWS has unparalleled insight into certain activities on the internet, in real time. For threat intelligence to have meaningful impact on security, large amounts of raw data from across the internet must be gathered and quickly analyzed. In addition, false positives must be purged. For example, threat intelligence findings could erroneously indicate an insider threat when an employee is logged accessing sensitive data after working hours, when in reality, that employee may have been tasked with a last-minute project and had to work overnight. Producing threat intelligence is very time consuming and requires substantial human and digital resources. Artificial intelligence (AI) and machine learning can help analysts sift through and analyze vast amounts of data. However, without the ability to collect and analyze relevant information across the entire internet, threat intelligence is not very useful. Even for organizations that are able to gather actionable threat intelligence on their own, without the reach of global-scale cloud infrastructure, it’s difficult or impossible for time-sensitive information to be collectively shared with others at a meaningful scale.

The AWS infrastructure radically transforms threat intelligence because we can significantly boost threat intelligence accuracy—what we refer to as high fidelity—because of the sheer number of intelligence signals (notifications generated by our security tools) we can observe. And we constantly improve our ability to observe and react to threat actors’ evolving tactics, techniques, and procedures (TTPs) as we discover and monitor potentially harmful activities through MadPot, our sophisticated globally-distributed network of honeypot threat sensors with automated response capabilities.

With our global network and internal tools such as MadPot, we receive and analyze thousands of different kinds of event signals in real time. For example, MadPot observes more than 100 million potential threats every day around the world, with approximately 500,000 of those observed activities classified as malicious. This means high-fidelity findings (pieces of relevant information) produce valuable threat intelligence that can be acted on quickly to protect customers around the world from harmful and malicious online activities. Our high-fidelity intelligence also generates real-time findings that are ingested into our intelligent threat detection security service Amazon GuardDuty, which automatically detects threats for millions of AWS accounts.

AWS’s Mithra ranks domain trustworthiness to help protect customers from threats

Let’s dive deeper. Identification of malicious domains (physical IP addresses on the internet) is crucial to effective threat intelligence. GuardDuty generates various kinds of findings (potential security issues such as anomalous behaviors) when AWS customers interact with domains, with each domain being assigned a reputation score derived from a variety of metrics that rank trustworthiness. Why this ranking? Because maintaining a high-quality list of malicious domain names is crucial to monitoring cybercriminal behavior so that we can protect customers. How do we accomplish the huge task of ranking? First, imagine a graph so large (perhaps one of the largest in existence) that it’s impossible for a human to view and comprehend the entirety of its contents, let alone derive usable insights.

Meet Mithra. Named after a mythological rising sun, Mithra is a massive internal neural network graph model, developed by AWS, that uses algorithms for threat intelligence. With its 3.5 billion nodes and 48 billion edges, Mithra’s reputation scoring system is tailored to identify malicious domains that customers come in contact with, so the domains can be ranked accordingly. We observe a significant number of DNS requests per day—up to 200 trillion in a single AWS Region alone—and Mithra detects an average of 182,000 new malicious domains daily. By assigning a reputation score that ranks every domain name queried within AWS on a daily basis, Mithra’s algorithms help AWS rely less on third parties for detecting emerging threats, and instead generate better knowledge, produced more quickly than would be possible if we used a third party.

Mithra is not only able to detect malicious domains with remarkable accuracy and fewer false positives, but this super graph is also capable of predicting malicious domains days, weeks, and sometimes even months before they show up on threat intel feeds from third parties. This world-class capability means that we can see and act on millions of security events and potential threats every day.

By scoring domain names, Mithra can be used in the following ways:

  • A high-confidence list of previously unknown malicious domain names can be used in security services like GuardDuty to help protect our customers. GuardDuty also allows customers to block malicious domains and get alerts for potential threats.
  • Services that use third-party threat feeds can use Mithra’s scores to significantly reduce false positives.
  • AWS security analysts can use scores for additional context as part of security investigations.

Sharing our high-fidelity threat intelligence with customers so they can protect themselves

Not only is our threat intelligence used to seamlessly enrich security services that AWS and our customers rely on, we also proactively reach out to share critical information with customers and other organizations that we believe may be targeted or potentially compromised by malicious actors. Sharing our threat intelligence enables recipients to assess information we provide, take steps to reduce their risk, and help prevent disruptions to their business.

For example, using our threat intelligence, we notify organizations around the world if we identify that their systems are potentially compromised by threat actors or appear to be running misconfigured systems vulnerable to exploits or abuse, such as open databases. Cybercriminals are constantly scanning the internet for exposed databases and other vulnerabilities, and the longer a database remains exposed, the higher the risk that malicious actors will discover and exploit it. In certain circumstances when we receive signals that suggest a third-party (non-customer) organization may be compromised by a threat actor, we also notify them because doing so can help head off further exploitation, which promotes a safer internet at large.

Often, when we alert customers and others to these kinds of issues, it’s the first time they become aware that they are potentially compromised. After we notify organizations, they can investigate and determine the steps they need to take to protect themselves and help prevent incidents that could cause disruptions to their organization or allow further exploitation. Our notifications often also include recommendations for actions organizations can take, such as to review security logs for specific domains and block them, implement mitigations, change configurations, conduct a forensic investigation, install the latest patches, or move infrastructure behind a network firewall. These proactive actions help organizations to get ahead of potential threats, rather than just reacting after an incident occurs.

Sometimes, the customers and other organizations we notify contribute information that in turn helps us assist others. After an investigation, if an affected organization provides us with related indicators of compromise (IOCs), this information can be used to improve our understanding of how a compromise occurred. This understanding can lead to critical insights we may be able to share with others, who can use it to take action to improve their security posture—a virtuous cycle that helps promote collaboration aimed at improving security. For example, information we receive may help us learn how a social engineering attack or particular phishing campaign was used to compromise an organization’s security to install malware on a victim’s system. Or, we may receive information about a zero-day vulnerability that was used to perpetrate an intrusion, or learn how a remote code execution (RCE) attack was used to run malicious code and other malware to steal an organization’s data. We can then use and share this intelligence to protect customers and other third parties. This type of collaboration and coordinated response is more effective when organizations work together and share resources, intelligence, and expertise.

Three examples of AWS high-fidelity threat intelligence in action

Example 1: We became aware of suspicious activity when our MadPot sensors indicated unusual network traffic known as backscatter (potentially unwanted or unintended network traffic that is often associated with a cyberattack) that contained known IOCs associated with a specific threat attempting to move across our infrastructure. The network traffic appeared to be originating from the IP space of a large multinational food service industry organization and flowing to Eastern Europe, suggesting potential malicious data exfiltration. Our threat intelligence team promptly contacted the security team at the affected organization, which wasn’t an AWS customer. They were already aware of the issue but believed they had successfully addressed and removed the threat from their IT environment. However, our sensors indicated that the threat was continuing and not resolved, showing that a persistent threat was ongoing. We requested an immediate escalation, and during a late-night phone call, the AWS CISO shared real-time security logs with the CISO of the impacted organization to show that large amounts of data were still being suspiciously exfiltrated and that urgent action was necessary. The CISO of the affected company agreed and engaged their Incident Response (IR) team, which we worked with to successfully stop the threat.

Example 2: Earlier this year, Volexity published research detailing two zero-day vulnerabilities in the Ivanti Connect Secure VPN, resulting in the publication of CVE-2023-46805 (an authentication-bypass vulnerability) and CVE-2024-21887 (a command-injection vulnerability found in multiple web components). The U.S. Cybersecurity and Infrastructure Security Agency (CISA) issued a cybersecurity advisory on February 29, 2024 on this issue. Earlier this year, Amazon security teams enhanced our MadPot sensors to detect attempts by malicious actors to exploit these vulnerabilities. Using information obtained by the MadPot sensors, Amazon identified multiple active exploitation campaigns targeting vulnerable Ivanti Connect Secure VPNs. We also published related intelligence in the GuardDuty common vulnerabilities and exposures (CVE) feed, enabling our customers who use this service to detect and stop this activity if it is present in their environment. (For more on CVSS metrics, see the National Institute of Standards and Technology (NIST) Vulnerability Metrics.)

Example 3: Around the time Russia began its invasion of Ukraine in 2022, Amazon proactively identified infrastructure that Russian threat groups were creating to use for phishing campaigns against Ukrainian government services. Our intelligence findings were integrated into GuardDuty to automatically protect AWS customers while also providing the information to the Ukrainian government for their own protection. After the invasion, Amazon identified IOCs and TTPs of Russian cyber threat actors that appeared to target certain technology supply chains that could adversely affect Western businesses opposed to Russia’s actions. We worked with the targeted AWS customers to thwart potentially harmful activities and help prevent supply chain disruption from taking place.

AWS operates the most trusted cloud infrastructure on the planet, which gives us a unique view of the security landscape and the threats our customers face every day. We are encouraged by how our efforts to share our threat intelligence have helped customers and other organizations be more secure, and we are committed to finding even more ways to help. Upcoming posts in this series will include other threat intelligence topics such as mean time to defend, our internal tool Sonaris, and more.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Max Peterson

CJ Moses
CJ Moses is the Chief Information Security Officer at Amazon. In his role, CJ leads security engineering and operations across Amazon. His mission is to enable Amazon businesses by making the benefits of security the path of least resistance. CJ joined Amazon in December 2007, holding various roles including Consumer CISO, and most recently AWS CISO, before becoming CISO of Amazon in September of 2023.

Prior to joining Amazon, CJ led the technical analysis of computer and network intrusion efforts at the Federal Bureau of Investigation’s Cyber Division. CJ also served as a Special Agent with the Air Force Office of Special Investigations (AFOSI). CJ led several computer intrusion investigations seen as foundational to the security industry today.

CJ holds degrees in Computer Science and Criminal Justice, and is an active SRO GT America GT2 race car driver.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/08/05/rapid7-introduces-exposure-command-to-eliminate-the-security-visibility-gap/

Exposure Command provides 360-degree visibility and enables security teams to pinpoint and extinguish your most critical risks.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

Security and IT teams are experiencing a significant (changed from “seismic” for clarity) shift in operations as they become more distributed. Development and procurement processes have decentralized, and sensitive data now extends far beyond the network edge. This expansion, coupled with growth and innovation outpacing security investments, has led to a significant “security visibility gap.”

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

Disparate tools widen this gap, creating data silos and inconsistencies, leading to manual efforts and swivel-charing to manually correlate conflicting findings and dashboards. This situation has been exacerbated by broader industry trends. Gartner estimates that through 2026, ‘unpatchable’ attack surfaces will grow from less than 10% to more than half of the enterprise’s total exposure, reducing the effectiveness of traditional vulnerability management programs.

Security teams need to manage and interpret a broad range of different exposure types – cloud misconfigurations, user entitlements, unmanaged machines, vulnerabilities, etc. with conflicting and duplicate data from various different security and IT management tools with varying levels of data fidelity.

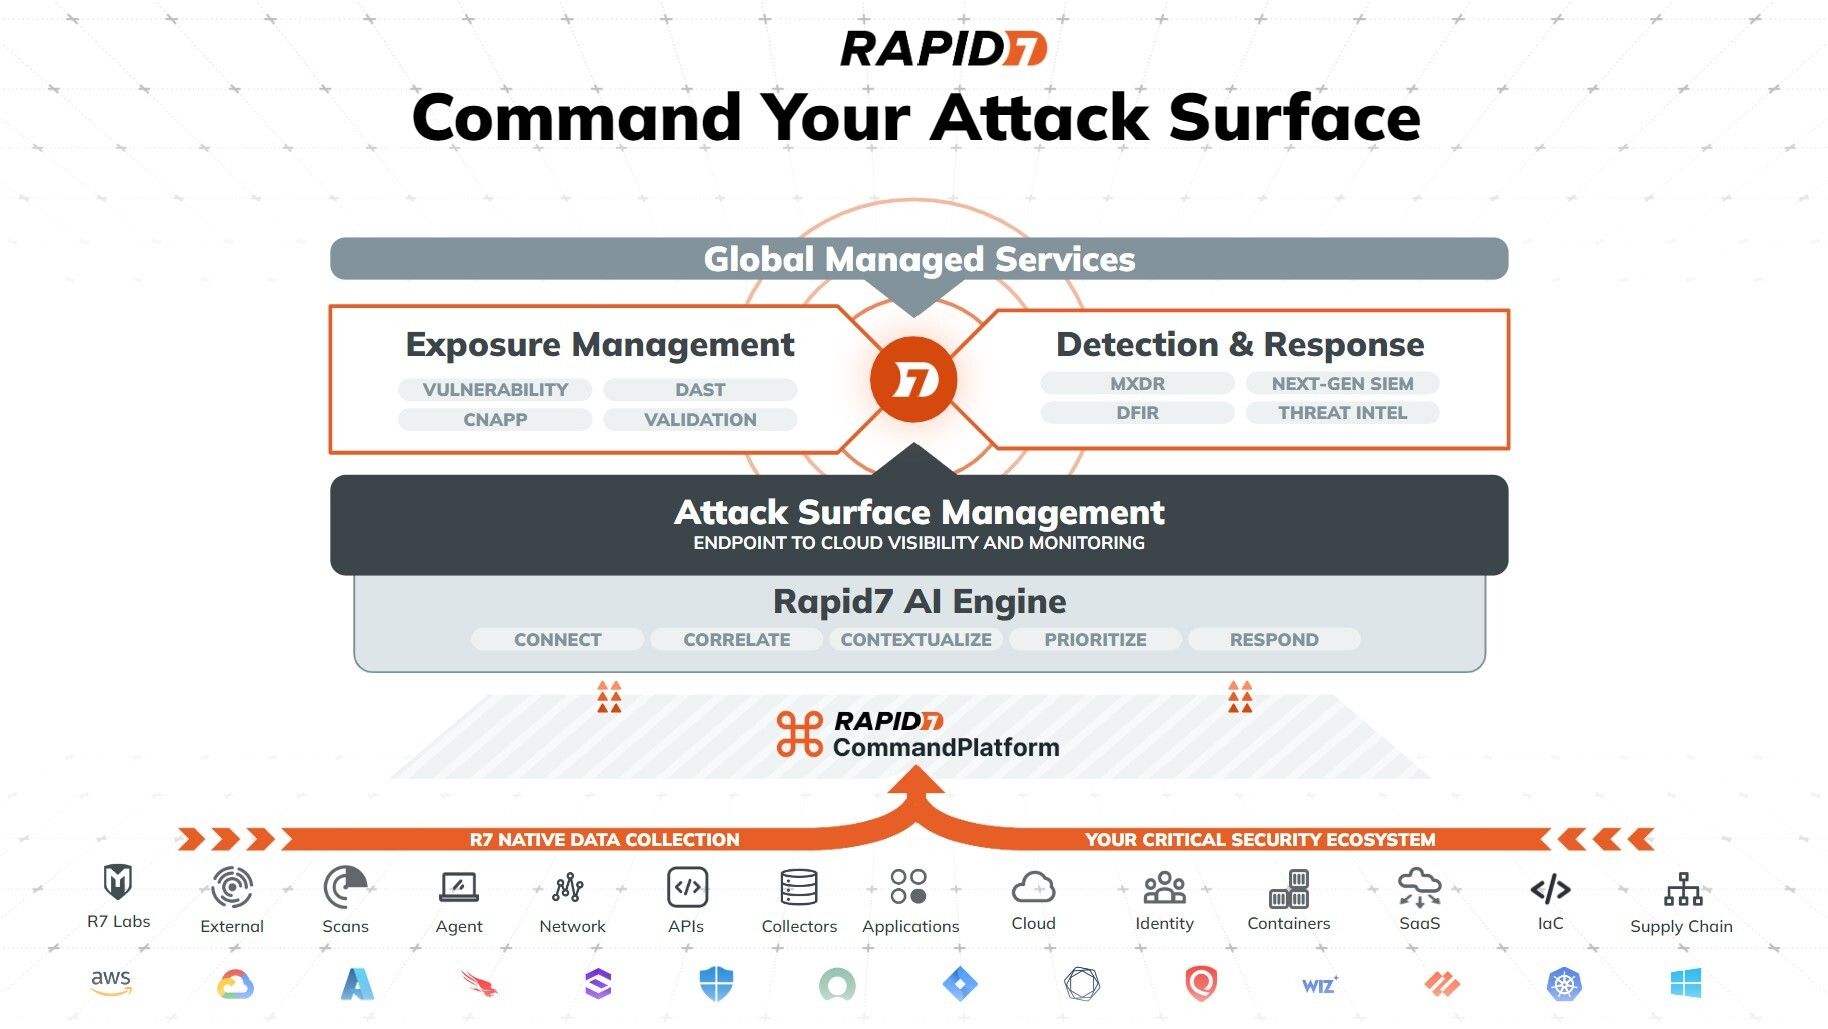
The only way to truly solve this problem is to implement a solution that treats third-party data as a first-class citizen, bringing together telemetry from all of your security tools to build a complete picture of your environment, and thereby your attack surface. To that end, Rapid7 announced the launch of two exciting new product offerings designed to unify your attack surface and deliver effective hybrid risk management: Surface Command and Exposure Command.

Unlock complete attack surface visibility to eliminate blind spots and uncover control gaps with Surface Command

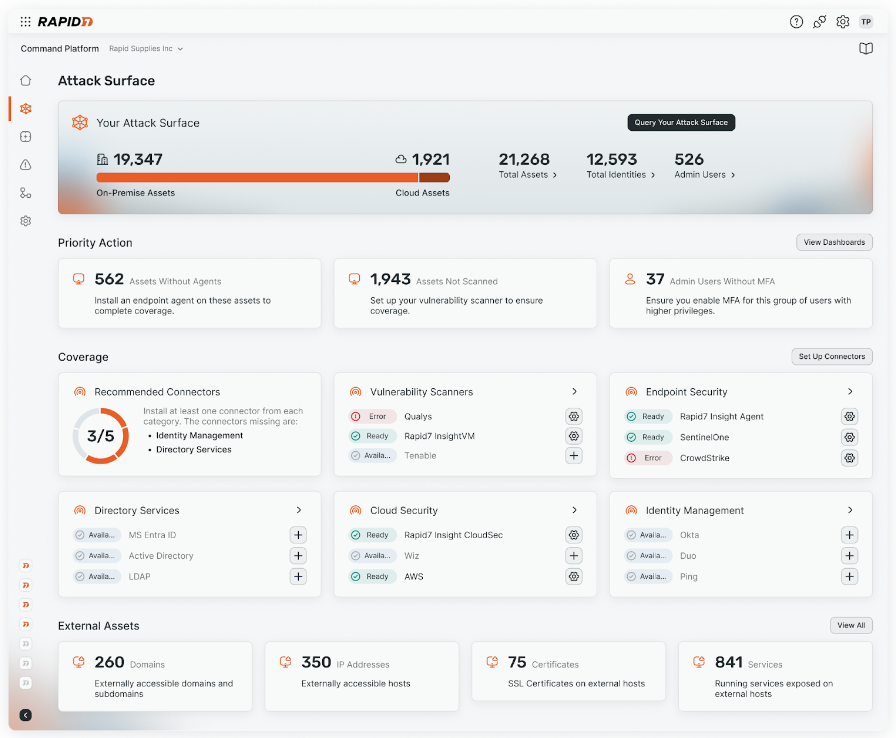
Surface Command closes the visibility gap by breaking down data silos, combining internal and external monitoring to build a 360-degree view of your entire environment, combining market leading Cyber Asset Attack Surface Management (CAASM) and External Attack Surface Management (EASM) capabilities into one unified offering.

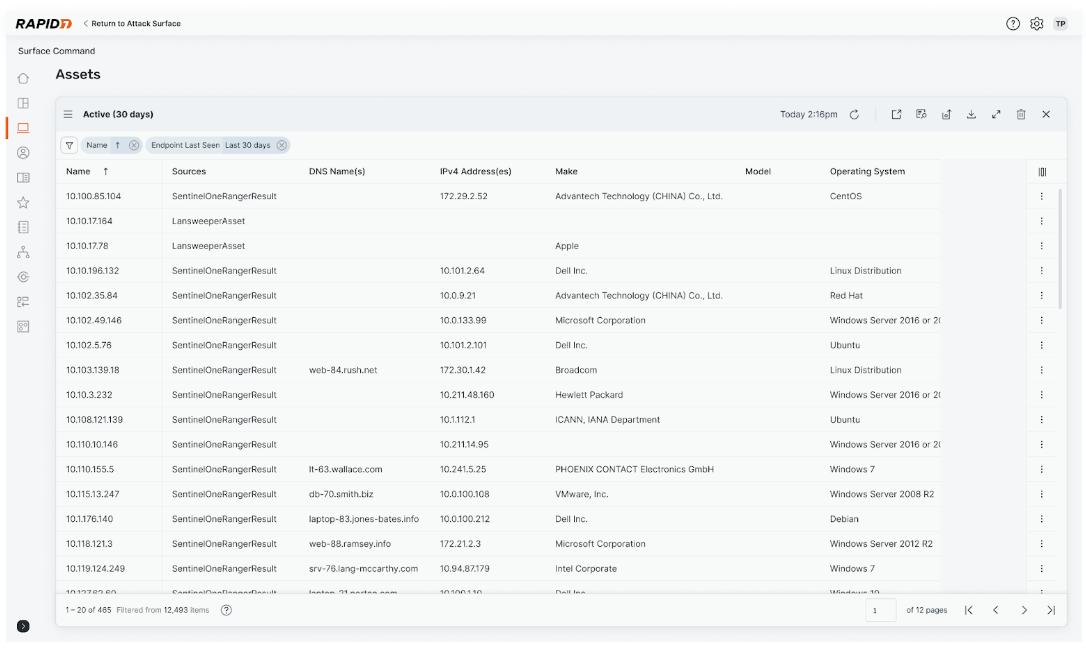
External scans provide an adversary’s perspective on the attack surface, detecting and validating exposures. Surface Command combines these external scans with a detailed inventory of your internal assets, continuously ingested and updated from a wide range of security and IT tools and automatically correlates the assets to create detailed inventory of your ‘true’ attack surface, highlighting security control gaps.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

This process delivers a comprehensive view of your environment that teams across the organization can trust and align on as a ‘single source of truth’ without the risk of blind spots, unprotected assets, and ungoverned access. Understanding how all your interconnected assets are configured enables you to quickly identify and prioritize  high-risk vulnerabilities, shadow IT, and compliance issues. With this more comprehensive visibility serving as the foundation of our Command Platform, security teams have a view of their attack surface they can trust and action across their wider organization.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

Automatically prioritize exposures across your hybrid environment with Exposure Command

Exposure Command extends the power of Surface Command even further, combining the same unified attack surface visibility with high-fidelity environment detail and risk context to help teams to zero-in on the exposures and vulnerabilities that attackers have in their sights with the threat-aware risk context needed to prioritize more efficiently and effectively.

With Exposure Command, every asset in your environment is enriched with relevant context from all of Rapid7’s exposure management capabilities, including our industry-leading VM, CNAPP and AppSec solutions, which provides teams an understanding of which assets are most critical to the business and those that suffer from toxic combinations that leave the organization vulnerable to a security incident.

This situational awareness allows teams to more effectively prioritize response efforts by honing in on the vulnerabilities that are either being actively exploited in the wild and/or those that present the most risk should a compromise occur.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

Prioritization is critical, especially when you consider the massive volume of risk signals produced by modern cloud-native environments on a daily basis. It’s simply not feasible to expect to address everything, so making sure that teams are spending the time they do have on the actions that will have the greatest impact on reducing their overall risk posture and eliminating critical exposures is key.

When it comes to prioritization, there are three primary vectors that we need to consider: Opportunity, Likelihood and Impact of exploitation.

  • Opportunity – The first step in prioritizing exposures is to understand whether a threat actor could exploit the issue in the first place by analyzing the downstream security controls and mechanisms in place – or not in place for that matter. This includes considering whether or not a resource is publicly accessible, if there are additional mitigating controls like web application or network firewalls, if an at-risk asset has an endpoint protection solution installed, etc.
  • Likelihood – It’s important to understand how likely it is that an attacker would exploit a given exposure. This can be accomplished in a number of ways, including focusing on CVEs on CISA’s Known Exploited Vulnerabilities (KEV) list, but also involves looking at real-world activity via threat intelligence feeds – like those that feed into Rapid7’s Active Risk score –  to get a sense for whether a vulnerability is being exploited elsewhere.
  • Impact – Taking into account the business criticality of the asset, data or system, what would be the relevant impact should a given risk signal be exploited by a threat actor. This is often accomplished by assigning tags that flag whether or not a given resource is associated with a business critical application or is housing sensitive customer data.

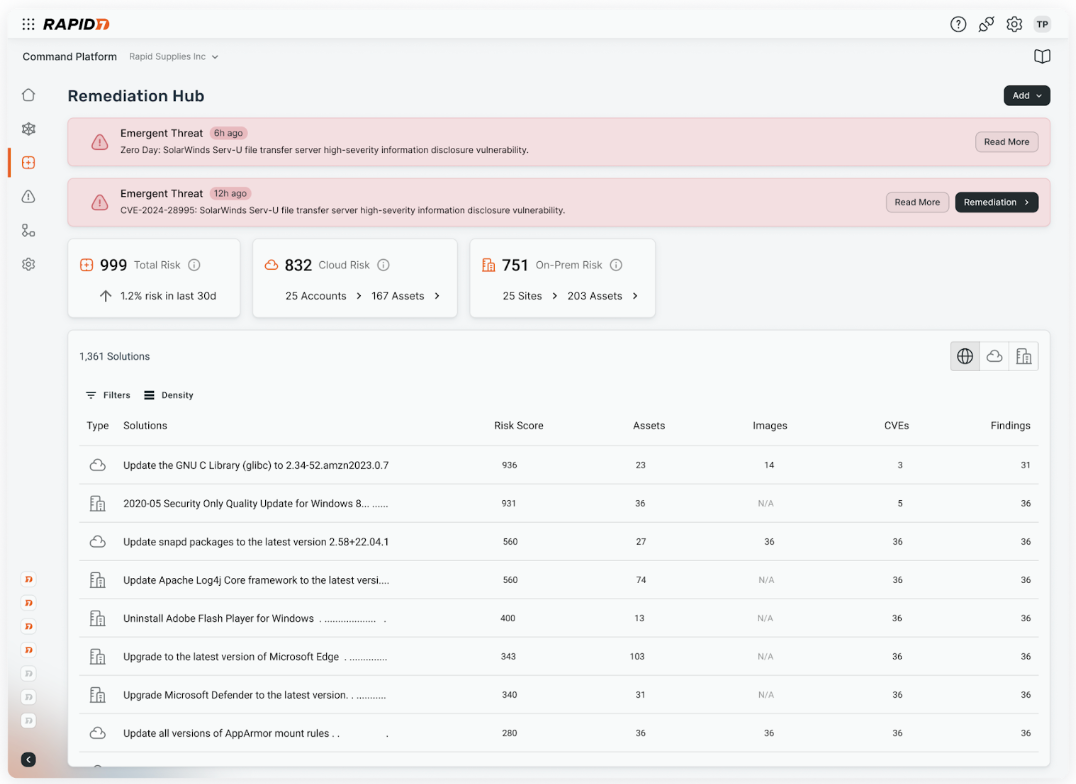
To this end, a new feature coming to the Command Platform with Exposure Command, Remediation Hub, automatically surfaces the top areas teams need to focus on and elevates the mitigation activities that would have the largest impact in reducing the overall risk score of your environment along with any relevant contextual information to assist in validation and remediation efforts.

Rapid7 Introduces Exposure Command to Eliminate the Security Visibility Gap

After 24+ years in exposure management, we are excited to partner with customers through the next era of the attack surface and hybrid risk with our new Exposure Command product. This is just the beginning. Stay tuned here for more updates as we continue to grow our Command Platform.

Learn more about Surface Command and Exposure Command

Attending Black Hat? Come see us at booth #2436 to get a one on one tour! If you can’t make it to the event you can also find additional information on the docs page, or give us a bit of information and we’ll have a member of the team reach out directly.

How we improved translation experience with cost efficiency

Post Syndicated from Grab Tech original https://engineering.grab.com/improved-translation-experience-with-cost-efficiency

Introduction

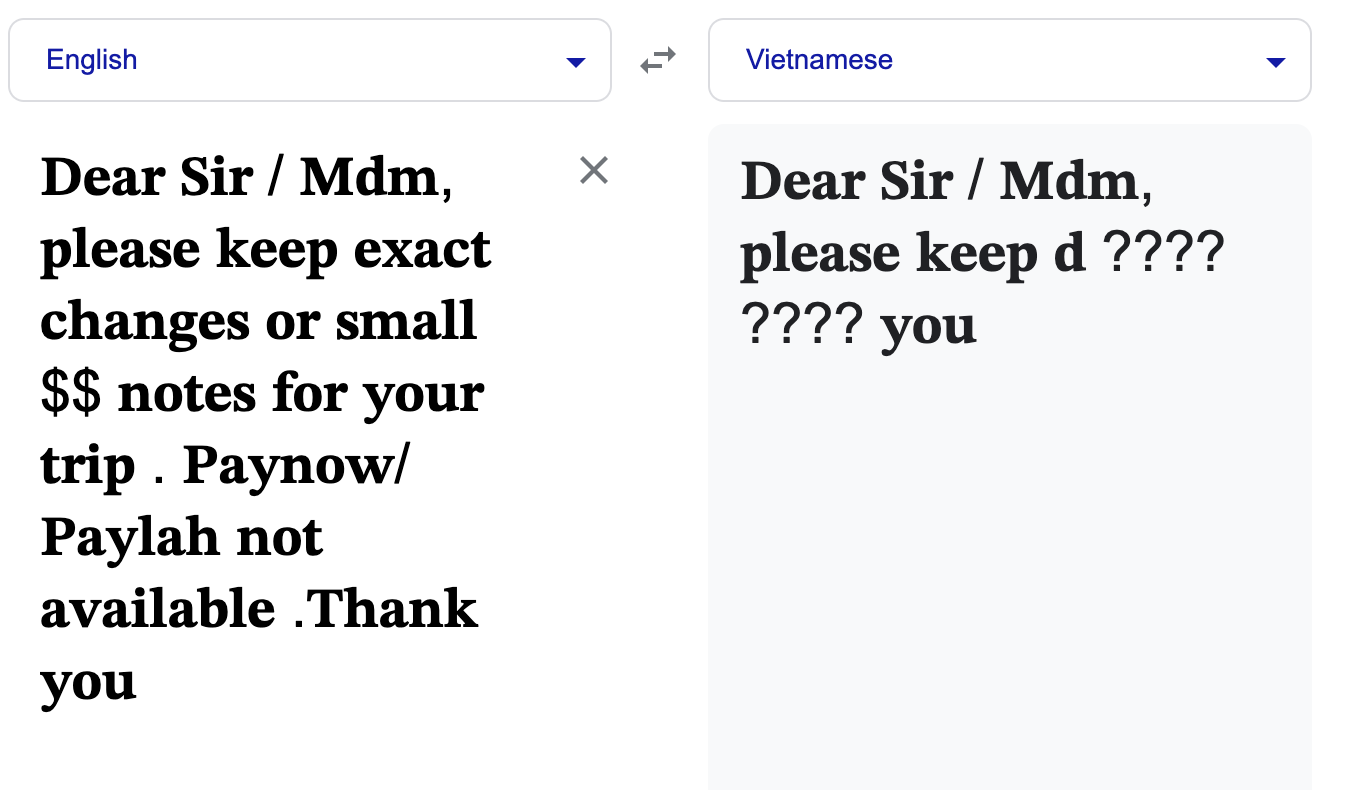
As COVID restrictions were fully lifted in 2023, the number of tourists grew dramatically. People began to explore the world again, frequently using the Grab app to make bookings outside of their home country. However, we noticed that communication posed a challenge for some users. Despite our efforts to integrate an auto-translation feature in the booking chat, we received feedback about occasional missed or inaccurate translations. You can refer to this blog for a better understanding of Grab’s chat system.

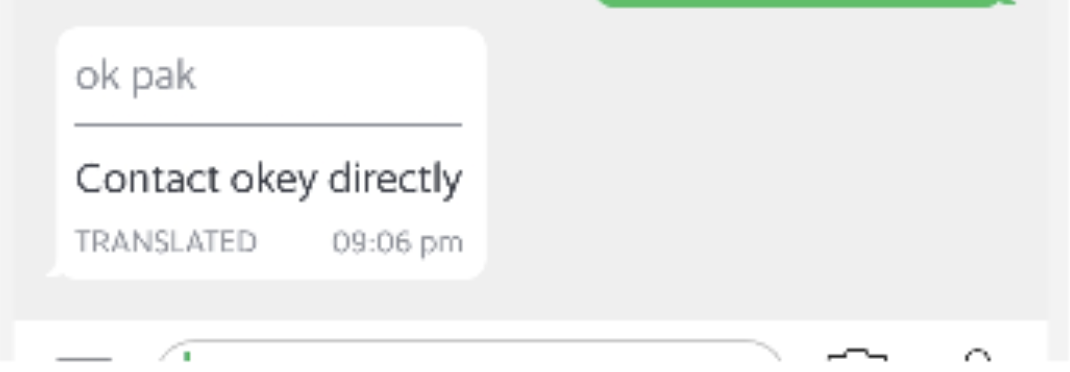
An example of a bad translation. The correct translation is: ‘ok sir’.

In an effort to enhance the user experience for travellers using the Grab app, we formed an engineering squad to tackle this problem. The objectives are as follows:

  • Ensure translation is provided when it’s needed.
  • Improve the quality of translation.
  • Maintain the cost of this service within a reasonable range.

Ensure translation is provided when it’s needed

Originally, we relied on users’ device language settings to determine if translation is needed. For example, if both the passenger and driver’s language setting is set to English, translation is not needed. Interestingly, it turned out that the device language setting did not reliably indicate the language in which a user would send their messages. There were numerous cases where despite having their device language set to English, drivers sent messages in another language.

Therefore, we needed to detect the language of user messages on the fly to make sure we trigger translation when it’s needed.

Language detection

Simple as it may seem, language detection is not that straightforward a task. We were unable to find an open-source language detector library that covered all Southeast Asian languages. We looked for Golang libraries as our service was written in Golang. The closest we could find were the following:

  • Whatlang: unable to detect Malay
  • Lingua: unable to detect Burmese and Khmer

We decided to choose Lingua over Whatlang as the base detector due to the following factors:

  • Overall higher accuracy.
  • Capability to provide detection confidence level.
  • We have more users using Malay than those using Burmese or Khmer.

When a translation request comes in, our first step is to use Lingua for language detection. If the detection confidence level falls below a predefined threshold, we fall back to call the third-party translation service as it can detect all Southeast Asian languages.

You may ask, why don’t we simply use the third-party service in the first place. It’s because:

  • The third-party service only has a translate API that also does language detection, but it does not provide a standalone language detection API.
  • Using the translate API is costly, so we need to avoid calling it when it’s unnecessary. We will cover more on this in a later section.

Another challenge we’ve encountered is the difficulty of distinguishing between Malay and Indonesian languages due to their strong similarities and shared vocabulary. The identical text might convey different meanings in these two languages, which the third-party translation service struggles to accurately detect and translate.

Differentiating Malay and Indonesian is a tough problem in general. However, in our case, the detection has a very specific context, and we can make use of the context to enhance our detection accuracy.

Making use of translation context

All our translations are for the messages sent in the context of a booking or order, predominantly between passenger and driver. There are two simple facts that can aid in our language detection:

  • Booking/order happens in one single country.
  • Drivers are almost always local to that country.

So, for a booking that happens in an Indonesian city, if the driver’s message is detected as Malay, it’s highly likely that the message is actually in Bahasa Indonesia.

Improve quality of translation

Initially, we were entirely dependent on a third-party service for translating our chat messages. While overall powerful, the third-party service is not perfect, and it does generate weird translations from time to time.

An example of a weird translation from a third-party service recorded on 19 Dec 2023.

Then, it came to us that we might be able to build an in-house translation model that could translate chat messages better than the third-party service. The reasons being:

  • The scope of our chat content is highly specific. All the chats are related to bookings or orders. There would not be conversations about life or work in the chat. Maybe a small Machine Learning (ML) model would suffice to do the job.
  • The third-party service is a general translation service. It doesn’t know the context of our messages. We, however, know the whole context. Having the right context gives us a great edge on generating the right translation.

Training steps

To create our own translation model, we took the following steps:

  • Perform topic modelling on Grab chat conversations.
  • Worked with the localisation team to create a benchmark set of translations.
  • Measured existing translation solutions against benchmarks.
  • Used an open source Large Language Model (LLM) to produce synthetic training data.
  • Used synthetic data to train our lightweight translation model.

Topic modelling

In this step, our aim was to generate a dataset which is both representative of the chat messages sent by our users and diverse enough to capture all of the nuances of the conversations. To achieve this, we took a stratified sampling approach. This involved a random sample of past chat conversation messages stratified by various topics to ensure a comprehensive and balanced representation.

Developing a benchmark

For this step we engaged Grab’s localisation team to create a benchmark for translations. The intention behind this step wasn’t to create enough translation examples to fully train or even finetune a model, but rather, it was to act as a benchmark for translation quality, and also as a set of few-shot learning examples for when we generate our synthetic data.

This second point was critical! Although LLMs can generate good quality translations, LLMs are highly susceptible to their training examples. Thus, by using a set of handcrafted translation examples, we hoped to produce a set of examples that would teach the model the exact style, level of formality, and correct tone for the context in which we plan to deploy the final model.

Benchmarking

From a theoretical perspective there are two ways that one can measure the performance of a machine translation system. The first is through the computation of some sort of translation quality score such as a BLEU or CHRF++ score. The second method is via subjective evaluation. For example, you could give each translation a score from 1 to 5 or pit two translations against each other and ask someone to assess which they prefer.

Both methods have their relative strengths and weaknesses. The advantage of a subjective method is that it corresponds better with what we want, a high quality translation experience for our users. The disadvantage of this method is that it is quite laborious. The opposite is true for the computed translation quality scores, that is to say that they correspond less well to a human’s subjective experience of our translation quality, but that they are easier and faster to compute.

To overcome the inherent limitations of each method, we decided to do the following:

  1. Set a benchmark score for the translation quality of various translation services using a CHRF++ score.
  2. Train our model until its CHRF++ score is significantly better than the benchmark score.
  3. Perform a manual A/B test between the newly trained model and the existing translation service.

Synthetic data generation

To generate the training data needed to create our model, we had to rely on an open source LLM to generate the synthetic translation data. For this task, we spent considerable effort looking for a model which had both a large enough parameter count to ensure high quality outputs, but also a model which had the correct tokenizer to handle the diverse sets of languages which Grab’s customers speak. This is particularly important for languages which use non-standard character sets such as Vietnamese and Thai. We settled on using a public model from Hugging Face for this task.

We then used a subset of the previously mentioned benchmark translations to input as few-shot learning examples to our prompt. After many rounds of iteration, we were able to generate translations which were superior to the benchmark CHRF++ scores which we had attained in the previous section.

Model fine tuning

We now had one last step before we had something that was production ready! Although we had successfully engineered a prompt capable of generating high quality translations from the public Hugging Face model, there was no way we’d be able to deploy such a model. The model was far too big for us to deploy it in a cost efficient manner and within an acceptable latency. Our solution to this was to fine-tune a smaller bespoke model using the synthetic training data which was derived from the larger model.

These models were language specific (e.g. English to Indonesian) and built solely for the purpose of language translation. They are 99% smaller than the public model. With approximately 10 Million synthetic training examples, we were able to achieve performance which was 98% as effective as our larger model.

We deployed our model and ran several A/B tests with it. Our model performed pretty well overall, but we noticed a critical problem: sometimes, numbers got mutated in the translation. These numbers can be part of an address, phone number, price etc. Showing the wrong number in a translation can cause great confusion to the users. Unfortunately, an ML model’s output can never be fully controlled; therefore, we added an additional layer of programmatic check to mitigate this issue.

Post-translation quality check

Our goal is to ensure non-translatable content such as numbers, special symbols, and emojis in the original message doesn’t get mutated in the translation produced by our in-house model. We extract all the non-translatable content from the original message, count the occurrences of each, and then try to match the same in the translation. If it fails to match, we discard the in-house translation and fall back to using the third-party translation service.

Keep cost low

At Grab, we try to be as cost efficient as possible in all aspects. In the case of translation, we tried to minimise cost by avoiding unnecessary on-the-fly translations.

As you would have guessed, the first thing we did was to implement caching. A cache layer is placed before both the in-house translation model and the third-party translation. We try to serve translation from the cache first before hitting the underlying translation service. However, given that translation requests are in free text and can be quite dynamic, the impact of caching is limited. There’s more we need to do.

For context, in a booking chat, other than the users, Grab’s internal services can also send messages to the chat room. These messages are called system messages. For example,our food service always sends a message with information on the food order when an order is confirmed.

System messages are all fairly static in nature, however, we saw a very high amount of translation cost attributed to system messages. Taking a deeper look, we noticed the following:

  • Many system messages were not sent in the recipient’s language, thus requiring on-the-fly translation.
  • Many system messages, though having the same static structure, contain quite a few variants such as passenger’s name and food order item name. This makes it challenging to utilise our translation cache effectively as each message is different.

Since all system messages are manually prepared, we should be able to get them all manually translated into all the required languages, and avoid on-the-fly translations altogether.

Therefore, we launched an internal campaign, mandating all internal services that send system messages to chat rooms to get manual translations prepared, and pass in the translated contents. This alone helped us save roughly US$255K a year!

Next steps

At Grab, we firmly believe that our proprietary in-house translation models are not only more cost-effective but cater more accurately to our unique use cases compared to third-party services. We will focus on expanding these models to more languages and countries across our operating regions.

Additionally, we are exploring opportunities to apply learnings of our chat translations to other Grab content. This strategy aims to guarantee a seamless language experience for our rapidly expanding user base, especially travellers. We are enthusiastically looking forward to the opportunities this journey brings!

Join us

Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Еретични мисли за професионалния спорт, олимпиадата и какво ни показа Юсуф Дикеч

Post Syndicated from VassilKendov original https://kendov.com/%D0%B5%D1%80%D0%B5%D1%82%D0%B8%D1%87%D0%BD%D0%B8-%D0%BC%D0%B8%D1%81%D0%BB%D0%B8-%D0%B7%D0%B0-%D0%BF%D1%80%D0%BE%D1%84%D0%B5%D1%81%D0%B8%D0%BE%D0%BD%D0%B0%D0%BB%D0%BD%D0%B8%D1%8F-%D1%81%D0%BF%D0%BE/

Еретични мисли за професионалния спорт, олимпиадата и какво ни показа Юсуф Дикеч

От доста време се каня да изложа еретичните си мисли за професионалния спорт, който гледаме и ползите от него за спортуващите и обществото. Предпоагам, че повечето хора няма да се съгласят, но то не е и нужно. Други пък изобщо няма да разберат, че говоря предимно за професионалния спорт, а не за масовия, но и това е нормално. Така или наче ще има хора, които ще успеят да хванат тезата, че към днешна дата ПРОФЕСИОНАЛНИЯТ СПОРТ носи позитиви само на спортиста и на организаторите на професионалните спортни събития.

Предполагам повечето от вас са чували за феномена на златната треска. Най-много пари от нея са заработили не залтотърсачите, а хората продаващи кирки и лопати, както и не безизвестния Леви Щраус, който прави дънките световно известно облекло, въпреки че основното им качество е зравината, заради което с апредпочитани от златотърсачите като работно облекло.

Така се получава и с професионалния спорт. На принципа на пирамидата – единици стават шампиони и успяват да осребрят усилията си, а милионите други остават с контузии, загубено време за трупане на други знания, утехата че са сформирали характер, който да им помага в живота като сладкари (примерно) или радостта, че са обиколили 10-тина държави по състезания и турнири.

Не така стои въпросът с всикчи останали, печелещи от техните щастието или нещастието на професионалните спортисти. Те наистина печелят. Ето някои сфери които наистина правят пари:

Собственици на спортни съоражения.

Без съмнение всеки спортист има нужда от спецални условия за да постигне „високо спортно майсторство“. Който се е занимавал със спорт знае, че лагерите и турнирите са неизбежна част от подготовката. Те обаче не са безплатни и отнемат доста време за пътувания. Моите наблюдения са, че последните години спортните клубове до които съм се докосвал, все по-често организират такива школи и турнири. Понякога за тях плащат спонсори, но това е много рядко. Повечето пъти кандидат професионалните състезатели плащат сами. Дори хореографските групи и групите по йога започнаха да правят лагер школи. Не ме разбирайте погрешно, но това са пари, които отиват при собствениците на съоръженията и огранизаторите, което също не е нещо ненормално, но за целта на анализа трябва да бъде отчетено. Все пак говорим за пари и ползи от професионалния спорт.
Преди време се бях зачел за кариерата на Григор Димитров и по-скоро за финансирането на подготовката му. Само да знаете, че човекът и семейството му бяха потънали в дългове до момента, в който не става Топ 3 в световната ранглиста. Това се случва през 2017. А можеше и да не се случи, както при много други.
За да стигне до това 3-то място, той посещава редица тенис академии и лагери, които определено не са безплатни. Преставяте ли си колко може да струва шведската академия „Good to Great“, която посещава през 2012-та. А треньори като Петер Лундгрен, Питър Макнамара и самият Патрик Муратоглу дали им е плащал една минимална работна заплата? Сино се съмнявам.

С две думи за да постигнеш върхови спортни успехи в днешно време, трябва да инвестираш страшно много пари. Преди 40 години не беше точно така и дори имаше изискване на олимпиадите да не участват професионални състезатели. В днешно време с масовизирането на спорта, медиите и пътуванията, парите за подготовка са неразделна част от бизнеса.

Телевизионни права

Професионалният спорт не би се развил толкова без медиите. Ако нямаше телевизии, зрителите не биха били толкова облъчвани. Знаете какво е, когато се предва футболен финал от някой турнир. Освен, че се бяга от работа за такова нещо, всички заведения слагат големи телевизори, та барем някоя агитка дойде да гледа мача при тях и остави някой лев.
Не казвам, че е лошо в никакъв случай, но дали сме наясно, че някъде в Б футболна група някой младеж се надява да стане звезда като Роналдо и влага цалото си време и енергия в това начинане при положение, че статистически това е много малко вероятно да се случи. Но пък финансовия и времеви ресурс са инвестирани и някой е спечелил от това.
Така или иначе телевизионните права са един от най-сигурните приходи на организаторите на спортни събития. За Олимпиадата в Париж, телевизионните права се очаква да донесат 3.3 млрд. долара на организаторите. Добре е нали? На фона на разходи от 10 млр. долара, 33% да са от ТВ права не е зле. Вижте как са се движили през годините приходите от ТВ права.

Атина 2004 – 1,5 млрд. долара
Пекин 2008 – 1,7 млрд. долара
Лондон 2012 – 2,6 млрд. долара
Рио 2016 – 2,9 млрд. долара
Токио 2020 – 3,1 млрд. долара

Имайте предвид, че са продадени над 8 млн. билета с очаквани приходи от едва 1.4 млр. долара. Тоест едва 14% от приходите се очаква да бъдат от зрители на място (и то ако няма печалба за организаторите). С други думи приходите от ТВ права са с около 140% по-високи от приходите от посетители на място.

продължава след бланката за среща
Моля използвайте приложената форма за записване на час за среща
[contact-form-7]

Мисля, че няма смисъл да давам повече примери кой и как печели от спорта. Със сигурност най-малкия % печалба е за състезателите, а рискът да не успеят да пробият,  клони към 100%. Разходите им за подготовка обаче са константа и то никак не малка, на фона на личните финанси и бюджети.

Юсуф Дикеч – новият символ на „олимпийския дух“

Харизматичен е Юсуф Дикеч – не може да се отрече. Скромен, без излишни емоции, с ясна полова ориентация… Качества които не са много толерирани или насърчавани от МОК. Поне съдейки по откриването на олимпиадата и всички скандали около нея. Но пък тези качества се харесват на хората.

Тук обаче има една подробност – тези качества се харесват, защото Юсуф стана шампион! Лицемерието в западното бщество е толкова голямо, че ако не беше се класирал на второ място, всички биха неглижирали тези му качества. Нека не забравяме, че в реалния живот той работи в сервиз – професия която не е най-уважаваната. С други думи „с тези качества – толкова“. Ако те не му бяха донесли второ място на олимпиада, никой никога не би им обърнал внимание, защото обществото не им обръща внимание и не ги цени. Цени ги само ако донесат някакви позитиви. Можду другото през 2016 на Олимпиадата в Рио, на същата дисциплина шампион става виетнамецът Hoang Xuan Vinh (не знам как се пише това на български). Същите качества, липса на допълнително оборудване, нооо никакво отразяване по медии и социални мрежи. Ето линк ако не вярвате – https://www.youtube.com/watch?v=d-Fv682oMZg


Мислих да опиша опиша съдбите и живота на няколко олимпийски шампиони, които познавам лично, след спиране на активната им спортна дейност, както и да ги сравня с живота на спртнит еминистри по което време са станали шампиони, но ще стане прекалено дълго. Мисля, че всички се сещате какви биха били изводите и разликите.

Не мога обаче да се сдържа и да спомена Гълъбин Боевски. Освен че лежа в затвор в Бразилия за трафик на наркотици, в момента пак е на топло по същата причина, само че в Португалия. Синът му пък беше задържат за разпространение на наркотици.
По-горе уточнихме колко се инвестира в един шампион и къде отива печалбата от него. Надали би се занимавал с разпространение на наркотици, ако можеше да печели достъчно от вдигане на щанги, след прекратяване на активна спортна дейност. Но как да печелиш от друго, като по времето когато е трябвало да формираш други умения, ти си бил по лагери и състезания?
Верно е, че други олимпийски шампиони се справят доста по-добре, но винаги в сферата на спорта, създавайки надежди в ново поколение, което пък инвестира в професионалния спорт. Тоест стават част от същата система, генерираща все повече приходи за школи, организатори на състезания, телевизии…

Без значение дали го разбираме или не, за всичко това е виновно финансирането. Ако в това общество се правят пари от професионален спорт, то медии, школи, комитети, клубове, стадиони и подготвителни центрове… десетки посредници по веригата ще правят пари от него.
От масовия спорт пари не се правят. Там хората спортуват за здраве, а това не изисква много разходи. Чувал ли е някой за победителя в ученическите първенства на джудо в Швейцария? Няма и да чуем. Ще чуем само ако е нещо „по-нестандартно“, да не кажа извратено. Примерно както в САЩ, ученическите първенства по борба бяха спечелени от момче, определило се като момиче или как във Финландия се е провело първенство по Hobby Horse Competition https://www.youtube.com/watch?v=RGnpWXtI3Q0

Като финал мога да кажа само – спортувайте за здраве! Професионалния спорт е по-скоро бизнес, а не здраве. Бизнес в който Вие сте продукта, в който търговеца обира печалбата от Вас!

Васил Кендов
Специалист по лични финанси
Планирайте за да не страдате

Моля използвайте приложената форма за записване на час за среща
[contact-form-7]


The post Еретични мисли за професионалния спорт, олимпиадата и какво ни показа Юсуф Дикеч appeared first on Kendov.com.

Седмицата (29 юли – 3 август)

Post Syndicated from Боряна Телбис original https://www.toest.bg/sedmitsata-29-yuli-3-avgust/

Седмицата (29 юли – 3 август)

„Тоест“ излиза в традиционната си августовска ваканция с един чудесен и вълнуващ брой. (Почти толкова вълнуващ, колкото Олимпиадата в Париж и всички съпътстващи я скандали, мистерии и активни мероприятия.) 

Започнахме седмицата с текста на Светла Енчева за трошенето на бариери отвъд океана и по-специално за една – тавана от най-дебело стъкло, този, чието пробиване води в Белия дом. Изглежда, Камала Харис се е устремила тъкмо към неговото разбиване. Ще стане ли Харис първата цветнокожа жена президент на Щатите? Предстои интересно политическо лято и напрегната есен и в САЩ.

За събитията от последния месец, довели до влизането (все още неофициално) на Харис в надпреварата за президент на САЩ, разказва Йоанна Елми в статията си „Пътеводител за летния политически хаос в САЩ“. „Лош месец за американската демокрация, но добър месец в историята на меметата – така обобщиха този юли потребителите в социалните мрежи в САЩ“, пише Йоанна, и да, поне на мемета се нагледахме. Ако имате нужда все пак и от някаква яснота за контекста, в който се раждат те – материалът на Йоанна Елми може да ви е много полезен.

Полезен за желаещите да вникнат в някои важни геополитически процеси безспорно е и текстът на Искрен Иванов, в който той анализира дружбата между Китай и Русия. С „Приятелство без граници. Как Китай очарова Русия?“ Искрен завършва кратката, но изключително съдържателна поредица за отношенията на далекоизточната страна с другите големи геополитически играчи – ЕС, САЩ и Русия. Ако сте пропуснали предишните две статии, може да ги прочетете тук и тук. 

Не е за изпускане и цялата поредица на Николета Атанасова „Пет отровни дела“. Тази седмица излиза последната част, в която Николета ни запознава със съдбата на Андрей Карпов, поредния руснак, избягал от режима на Путин и попаднал в кошмарната система на ДАБ, чиито административни „лабиринти“ напомнят на готическа цитадела, предвидена за мъчения и унижения.

Като стана дума за мъчения и унижения, някак плавно преместваме вниманието си към политическия анализ на Емилия Милчева. Да се чуди човек защо българската политическа действителност навява подобни асоциации… 

В статията на Емилия става дума за Делян Пеевски в ролята на разобличител, готов да демаскира цялата политическа класа, защото, както знаем, компромати (ще) има за всички от сърце. Най-големият проблем обаче е, че ако Делян Пеевски ще руши порочния модел, от който сам е част, казвайки „истината, цялата истина или поне 30% от нея“ (по Румен Белчев), едва ли ще го добутаме до по-светли времена. 

От друга страна пък, има къде-къде по-важни работи, в които можем да се вглъбим, за да си обзаведем спокойно паралелна реалност, където всички разбираме от спорт, изкуство, генетика и каквото друго падне от световния кликбейт обмен.

Но понеже ние сме малко скарани с кликбейт аранжимента, продължаваме с бързия седмичен обзор на текстовете в „Тоест“, който ни кара да си купим билет за Тайланд, да се качим на самолета и да не се върнем никога повече. И ако нашият авантюризъм ще катастрофира безславно до 10–15 минути, то вашият може да се окаже от много по-устойчив вид и току-виж наистина ви завел в Тайланд или където другаде искате. 

Преди това прочетете какво разказва тъкмо за тази страна в Югоизточна Азия Емине Садкъ. Във втората част на „Тайланд под кожата“ става въпрос за непоносимата жега, за 36-те тоналности на тайския език, за местната фауна, която няма нищо общо с илюстрованите книжки, и за един забележителен турнир по тенис на маса. Задължително започнете обаче с първата част, защото Емине описва тази уж все по-позната туристическа дестинация така, че ние от обикновени читатели се превръщаме в синестети, които вкусват цветове и миришат думи.

Оставаме в източното полукълбо и с рубриката „На второ четене“, в която тази седмица имаме текст от Стефан Иванов. Той препоръчва книгата „Изтокът“ на поляка Анджей Сташук. За него Стефан казва:

… писането му е освобождаващо, в него няма перверзна и популистка носталгия, суетна тъга или снизходителност.
Налице са единствено желание да се преброди географията с широко отворени очи и с пуснати шлюзове, за да може паметта да потече и да напои градината или гората, каквато тази книга всъщност е. Гора на паметта, в която източните страни са влюбени в националните си катастрофи, а не в свободата или справедливостта, и градина на днешната несигурност, в която границите са паднали, но цъфти буренът на национализма.

Такъв беше „Тоест“ тази седмица. Желаем ви спокойно лято без напънато щастие за социалните медии и без клишета за следобеди на годината, но с достатъчно моменти, в които не знаете къде ви е телефонът, защото всичко, което ви трябва, е точно до вас. Нека не забравяме все пак, че човек може да е нещастен и през август, но е по-малко вероятно.

Благодарим ви, че сме заедно! Продължаваме да разчитаме на вашата безценна финансова подкрепа, за да създаваме съдържанието, заради което сте наши читатели.

До нови срещи наесен.

The collective thoughts of the interwebz