[$] When ELF notes reveal too much

Post Syndicated from corbet original https://lwn.net/Articles/962782/

The Linux kernel uses a number of hardening techniques to try to protect
itself against compromise; one of those is kernel address-space layout
randomization (KASLR). But randomization is of little benefit if the
kernel spills the beans on where its code has ended up. As it happens, the
kernel has been doing exactly that — since 2007, in a behavior that
predates the addition of KASLR. Some changes are in the
works to close that hole, but it is illustrative of just how hard some
secrets are to keep.

Security updates for Thursday

Post Syndicated from jake original https://lwn.net/Articles/963205/

Security updates have been issued by CentOS (python-pillow), Debian (firefox-esr and imagemagick), Fedora (kernel, mbedtls, rust-asyncgit, rust-bat, rust-cargo-c, rust-eza, rust-git-absorb, rust-git-delta, rust-git2, rust-gitui, rust-libgit2-sys, rust-lsd, rust-pore, rust-pretty-git-prompt, rust-shadow-rs, rust-silver, rust-tokei, and rust-vergen), Gentoo (LibreOffice), Red Hat (kpatch-patch), Slackware (mozilla), SUSE (docker, python-pycryptodome, python3, and qemu), and Ubuntu (firefox and linux, linux-aws, linux-aws-5.4, linux-bluefield, linux-gcp, linux-gkeop,
linux-hwe-5.4, linux-ibm, linux-ibm-5.4, linux-iot, linux-kvm,
linux-oracle, linux-oracle-5.4, linux-raspi, linux-raspi-5.4,
linux-xilinx-zynqmp).

Enhancing security analysis with Cloudflare Zero Trust logs and Elastic SIEM

Post Syndicated from Corey Mahan original https://blog.cloudflare.com/enhancing-security-analysis-with-cloudflare-zero-trust-logs-and-elastic-siem


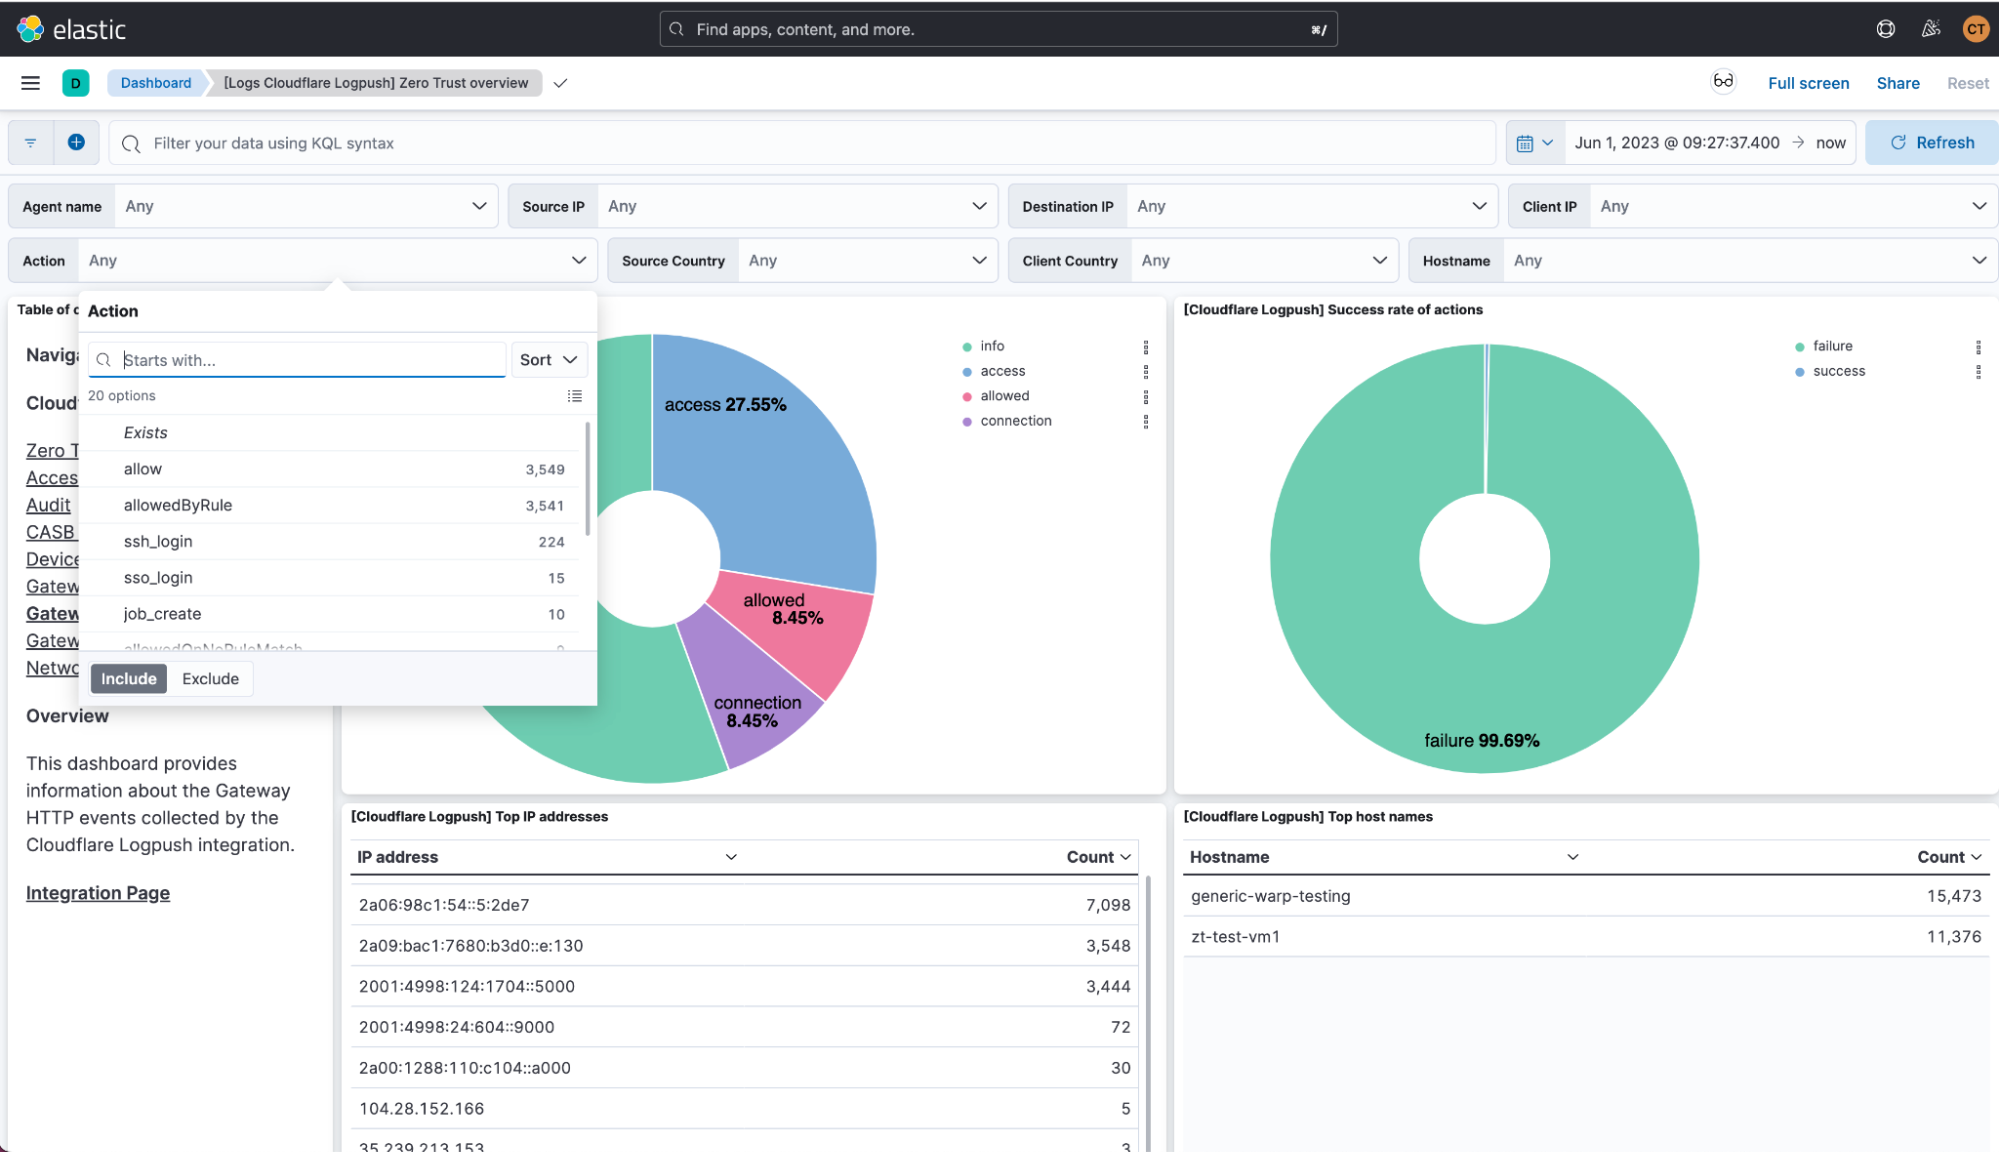
Today, we are thrilled to announce new Cloudflare Zero Trust dashboards on Elastic. Shared customers using Elastic can now use these pre-built dashboards to store, search, and analyze their Zero Trust logs.

When organizations look to adopt a Zero Trust architecture, there are many components to get right. If products are configured incorrectly, used maliciously, or security is somehow breached during the process, it can open your organization to underlying security risks without the ability to get insight from your data quickly and efficiently.

As a Cloudflare technology partner, Elastic helps Cloudflare customers find what they need faster, while keeping applications running smoothly and protecting against cyber threats. “I’m pleased to share our collaboration with Cloudflare, making it even easier to deploy log and analytics dashboards. This partnership combines Elastic’s open approach with Cloudflare’s practical solutions, offering straightforward tools for enterprise search, observability, and security deployment,” explained Mark Dodds, Chief Revenue Officer at Elastic.

Value of Zero Trust logs in Elastic

With this joint solution, we’ve made it easy for customers to seamlessly forward their Zero Trust logs to Elastic via Logpush jobs. This can be achieved directly via a Restful API or through an intermediary storage solution like AWS S3 or Google Cloud. Additionally, Cloudflare’s integration with Elastic has undergone improvements to encompass all categories of Zero Trust logs generated by Cloudflare.

Here are detailed some highlights of what the integration offers:

  • Comprehensive Visibility: Integrating Cloudflare Logpush into Elastic provides organizations with a real-time, comprehensive view of events related to Zero Trust. This enables a detailed understanding of who is accessing resources and applications, from where, and at what times. Enhanced visibility helps detect anomalous behavior and potential security threats more effectively, allowing for early response and mitigation.
  • Field Normalization: By unifying data from Zero Trust logs in Elastic, it’s possible to apply consistent field normalization not only for Zero Trust logs but also for other sources. This simplifies the process of search and analysis, as data is presented in a uniform format. Normalization also facilitates the creation of alerts and the identification of patterns of malicious or unusual activity.
  • Efficient Search and Analysis: Elastic provides powerful data search and analysis capabilities. Having Zero Trust logs in Elastic enables quick and precise searching for specific information. This is crucial for investigating security incidents, understanding workflows, and making informed decisions.
  • Correlation and Threat Detection: By combining Zero Trust data with other security events and data, Elastic enables deeper and more effective correlation. This is essential for detecting threats that might go unnoticed when analyzing each data source separately. Correlation aids in pattern identification and the detection of sophisticated attacks.
  • Prebuilt Dashboards: The integration provides out-of-the-box dashboards offering a quick start to visualizing key metrics and patterns. These dashboards help security teams visualize the security landscape in a clear and concise manner. The integration not only provides the advantage of prebuilt dashboards designed for Zero Trust datasets but also empowers users to curate their own visualizations.

What’s new on the dashboards

One of the main assets of the integration is the out-of-the-box dashboards tailored specifically for each type of Zero Trust log. Let’s explore some of these dashboards in more detail to find out how they can help us in terms of visibility.

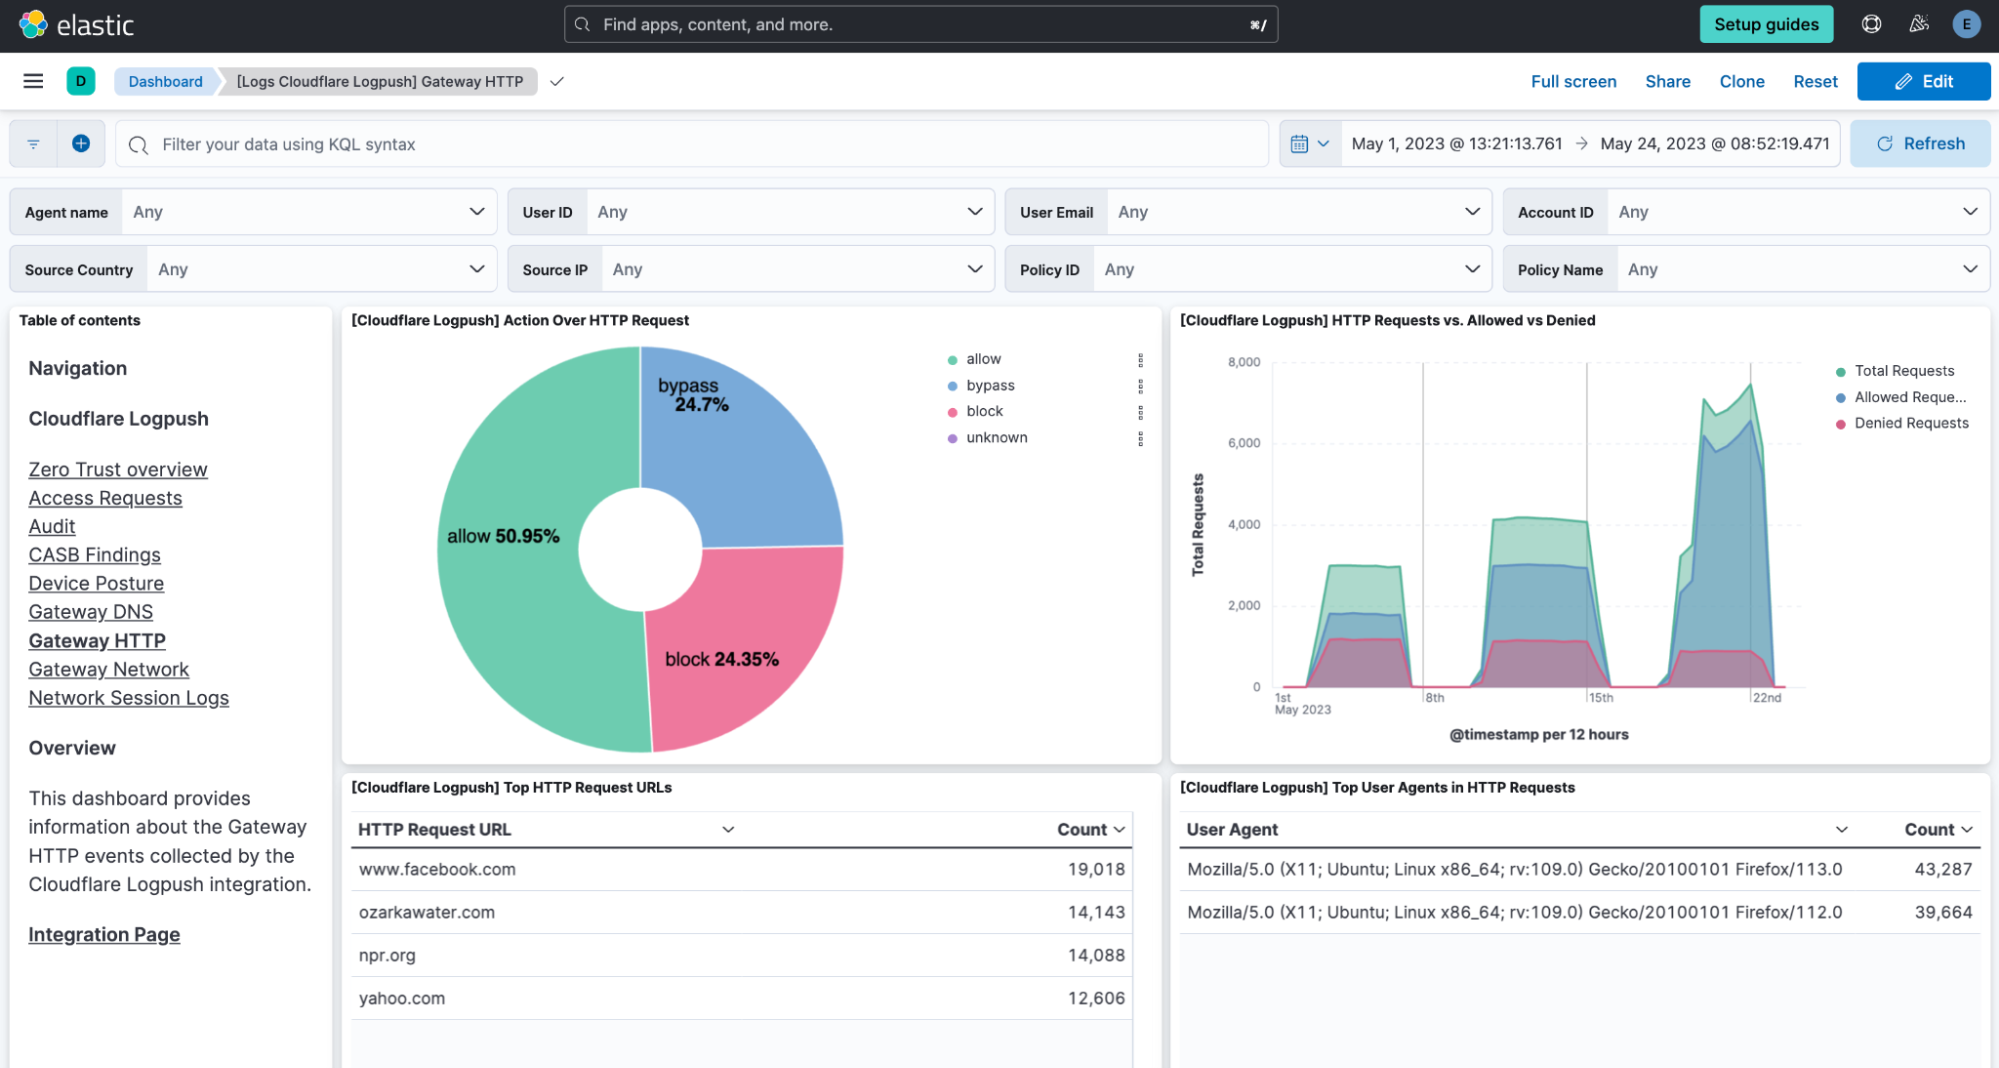
Gateway HTTP

This dashboard focuses on HTTP traffic and allows for monitoring and analyzing HTTP requests passing through Cloudflare’s Secure Web Gateway.

Here, patterns of traffic can be identified, potential threats detected, and a better understanding gained of how resources are being used within the network.

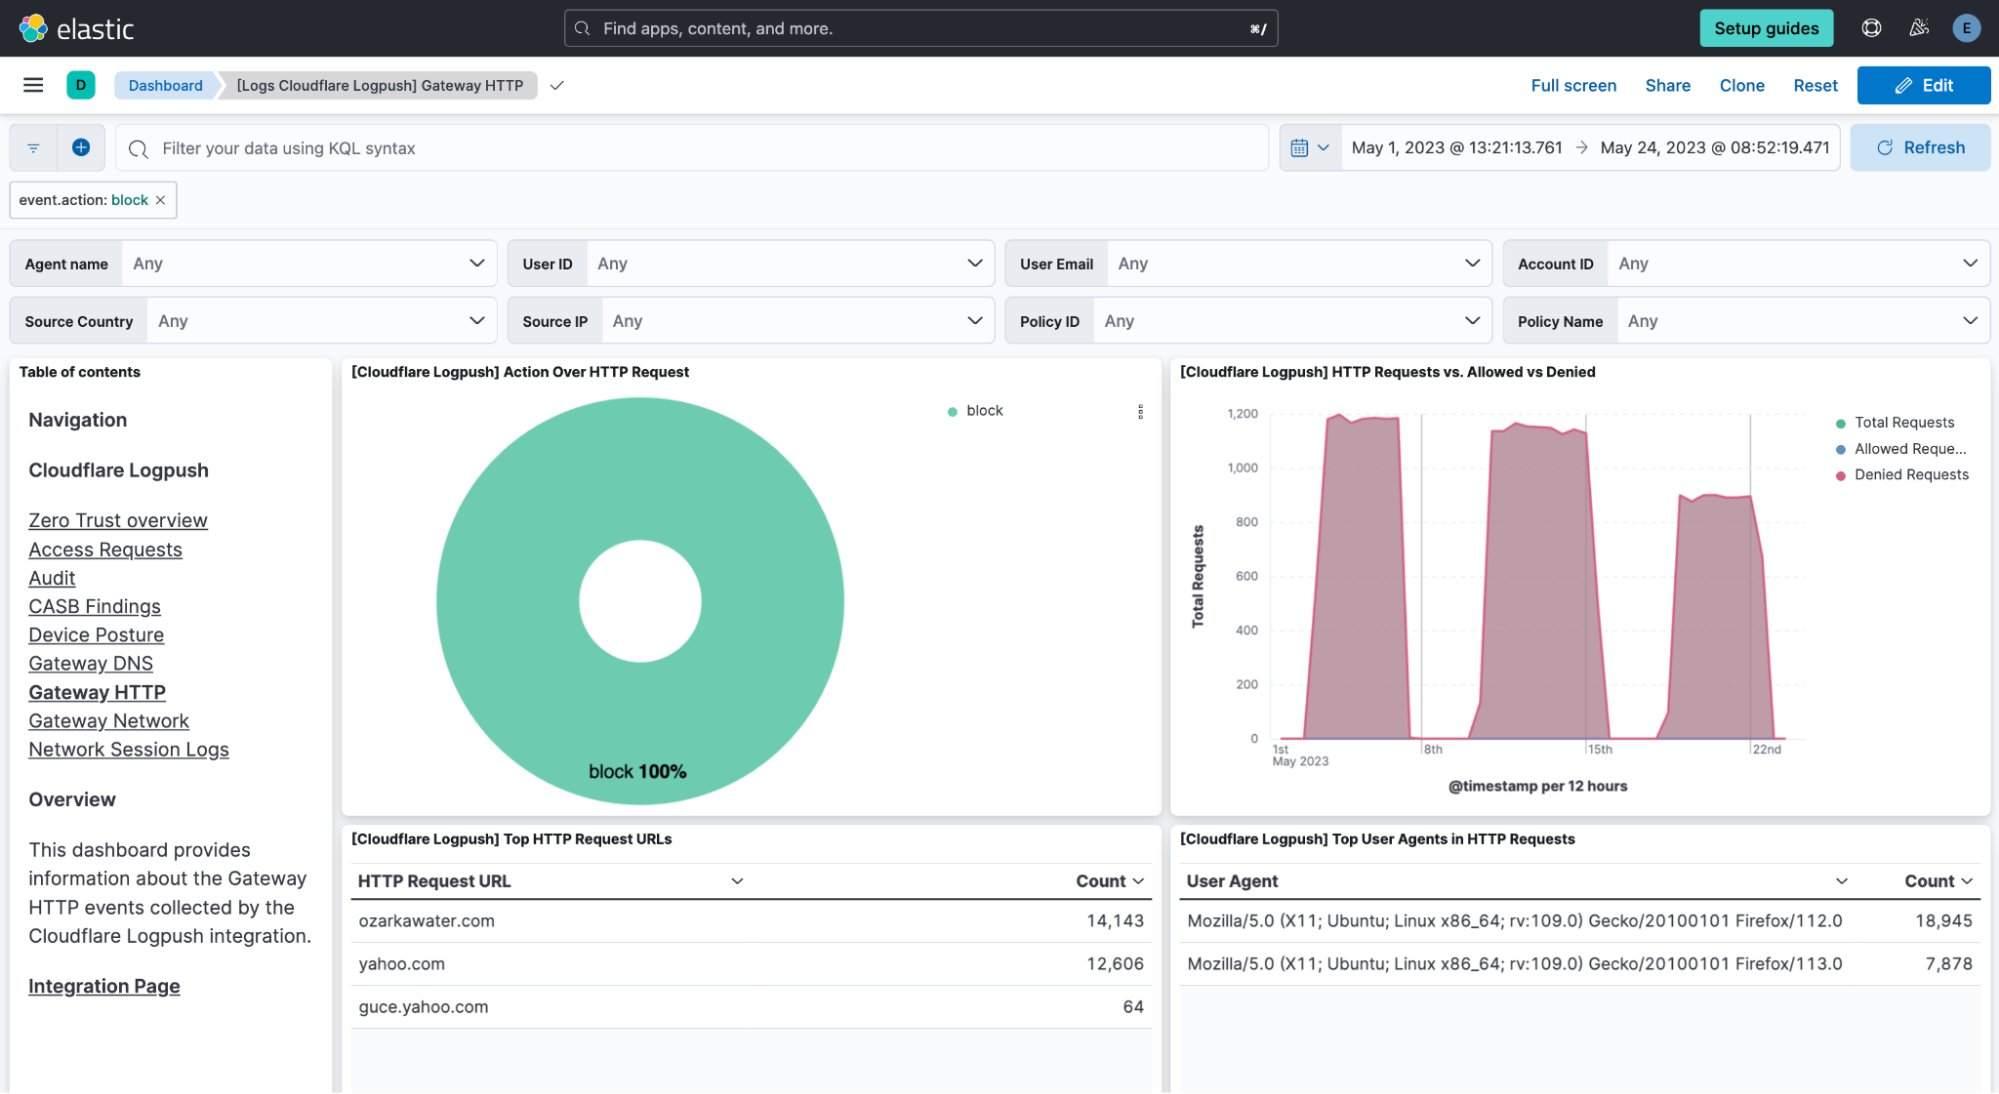
Every visualization in the stage is interactive. Therefore, the whole dashboard adapts to enabled filters, and they can be pinned across dashboards for pivoting. For instance, if clicking on one of the sections of the donut showing the different actions, a filter is automatically applied on that value and the whole dashboard is oriented around it.

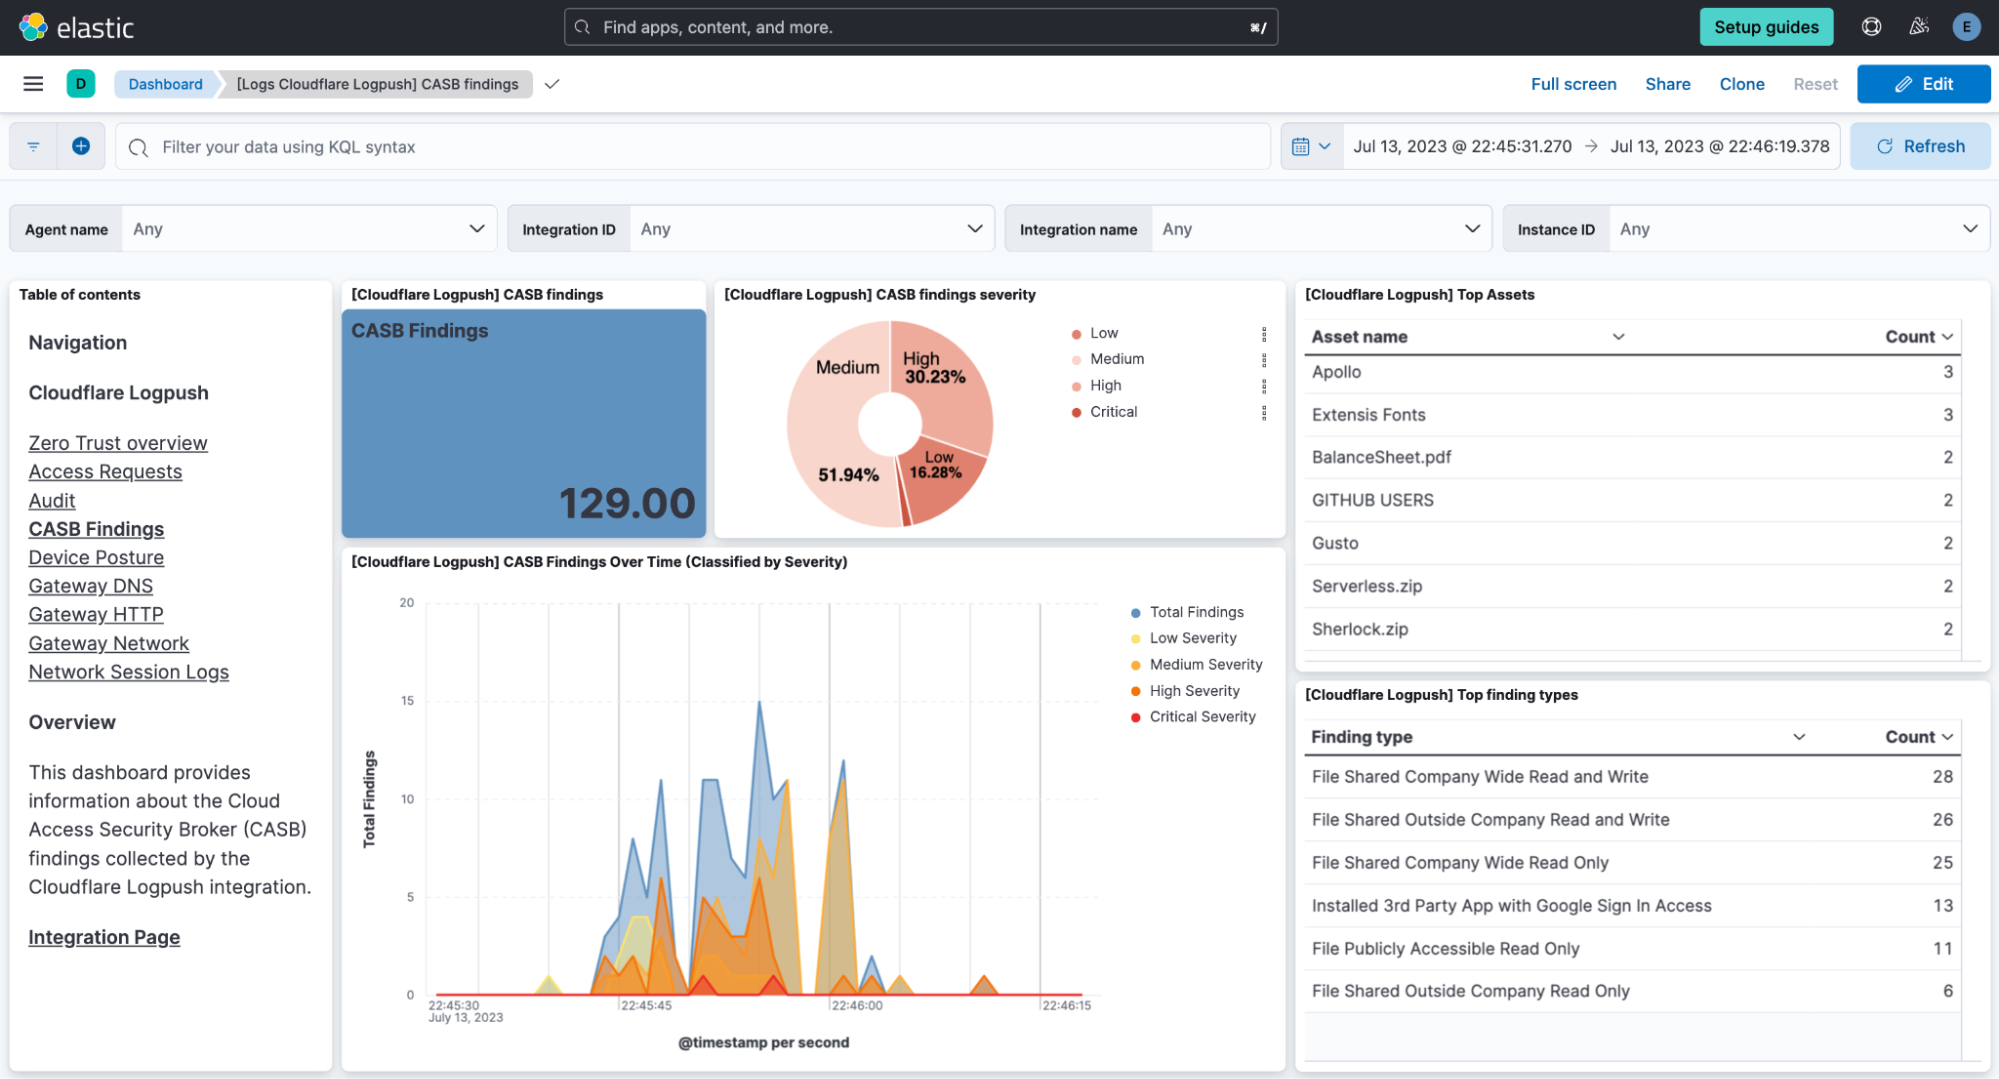
CASB

Following with a different perspective, the CASB (Cloud Access Security Broker) dashboard provides visibility over cloud applications used by users. Its visualizations are targeted to detect threats effectively, helping in the risk management and regulatory compliance.

These examples illustrate how dashboards in the integration between Cloudflare and Elastic offer practical and effective data visualization for Zero Trust. They enable us to make data-driven decisions, identify behavioral patterns, and proactively respond to threats. By providing relevant information in a visual and accessible manner, these dashboards strengthen security posture and allow for more efficient risk management in the Zero Trust environment.

How to get started

Setup and deployment is simple. Use the Cloudflare dashboard or API to create Logpush jobs with all fields enabled for each dataset you’d like to ingest on Elastic. There are eight account-scoped datasets available to use today (Access Requests, Audit logs, CASB findings, Gateway logs including DNS, Network, HTTP; Zero Trust Session Logs) that can be ingested into Elastic.

Setup Logpush jobs to your Elastic destination via one of the following methods:

  • HTTP Endpoint mode – Cloudflare pushes logs directly to an HTTP endpoint hosted by your Elastic Agent.
  • AWS S3 polling mode – Cloudflare writes data to S3 and Elastic Agent polls the S3 bucket by listing its contents and reading new files.
  • AWS S3 SQS mode – Cloudflare writes data to S3, S3 pushes a new object notification to SQS, Elastic Agent receives the notification from SQS, and then reads the S3 object. Multiple Agents can be used in this mode.

Enabling the integration in Elastic

  1. In Kibana, go to Management > Integrations
  2. In the integrations search bar type Cloudflare Logpush.
  3. Click the Cloudflare Logpush integration from the search results.
  4. Click the Add Cloudflare Logpush button to add Cloudflare Logpush integration.
  5. Enable the Integration with the HTTP Endpoint, AWS S3 input or GCS input.
  6. Under the AWS S3 input, there are two types of inputs: using AWS S3 Bucket or using SQS.
  7. Configure Cloudflare to send logs to the Elastic Agent.

What’s next

As organizations increasingly adopt a Zero Trust architecture, understanding your organization’s security posture is paramount. The dashboards help with necessary tools to build a robust security strategy, centered around visibility, early detection, and effective threat response.  By unifying data, normalizing fields, facilitating search, and enabling the creation of custom dashboards, this integration becomes a valuable asset for any cybersecurity team aiming to strengthen their security posture.

We’re looking forward to continuing to connect Cloudflare customers with our community of technology partners, to help in the adoption of a Zero Trust architecture.

Explore this new integration today.

The Zabbix/HackerOne Bug Bounty Program: A Year of Results

Post Syndicated from Michael Kammer original https://blog.zabbix.com/the-zabbix-hackerone-bug-bounty-program-a-year-of-results/27490/

As cyberattacks increase exponentially and the cost of maintaining dedicated internal security teams skyrockets, the popularity of the “bug bounty” program (which sees outside hackers paid by organizations to legally expose cybersecurity vulnerabilities) is exploding.

Organizations large and small are running programs to root out the security vulnerabilities in their products. Governments and policymakers are changing laws to make the approach easier to adopt, while private sector tech giants are also offering generous rewards – Apple alone has reportedly paid out more than $20 million via its bounty program, and the vendor offers up to $2 million to any hacker who reports a vulnerability that bypasses the protections of Lockdown Mode on its devices.

It’s an approach that dovetails perfectly with the Zabbix philosophy of “security first,” and it’s why as 2023 dawned we began working with HackerOne, the world leader in attack resistance management (ARM). ARM blends the security expertise of ethical hackers with asset discovery, continuous assessment, and process enhancement to find and close gaps in the digital attack surface.

Why HackerOne?

We knew from the start that we wanted to create a Zabbix-specific bug bounty program that would challenge the world’s best ethical hackers to find the weak spots in our cybersecurity armor – and let us know about them in time to fix them.

One of the biggest advantages of the HackerOne platform is the broad and diverse community of experts that they can call on. Adding Zabbix to HackerOne’s platform was a golden opportunity to test our security and vulnerabilities on a scale that we’d previously been unable to even imagine.

In contrast to an individual penetration test, which is the “old-school” industry standard security measure and is performed based on a pre-prepared scenario, we knew that HackerOne’s experts could discover vulnerabilities that a run-of-the-mill penetration test would never find.

At the same time, we knew that adding Zabbix to HackerOne was a bold decision that would test our faith in the security of our product. Put simply, teaming up with HackerOne was our way of confirming the quality of Zabbix and our desire to constantly improve it.

Getting started

We’ve known for a long time that HackerOne was the ideal partner for a bug bounty program, given their reputation for innovation and effectiveness. After an initial approach and agreement between HackerOne and Zabbix, it was time to consider what exactly a Zabbix bug bounty program would look like.

It was clear to everyone involved that if the reporting of vulnerabilities was to be meaningful and structured, we needed to develop new workflows that would provide a procedure for processing the received applications and handing them over for development. Another critical step was to register for the Common Vulnerabilities and Exposures (CVE) database, where all vulnerabilities discovered in Zabbix are currently registered.

The results

We’re pleased to report that as with any successful implementation, the numbers speak for themselves:

Data for the period 01.01.2023 – 25.01.2024

Submissions

• Reports submitted: 250
• Reports triaged: 3
• Reports closed as resolved: 16
• Reports rewarded: 19

Rewards

• Total rewards: $17,300.00
• Average reward: $865.00
• Median reward: $500.00

Submissions by severity

• Critical: 29
• High: 65
• Medium, low, none: 108
• Not severe: 48

We were pleasantly surprised at the sheer number of submissions alone – not all 250 submissions were severe or even actionable, but the number shows that our community is taking to the program, spreading the word, and doing their part to help us make sure that Zabbix is as secure as we can possibly make it. The fact that we were able to “squash” several bugs that will now never get a chance to bedevil our users is just the icing on the cake.

The results are impressive, but in keeping with the Zabbix ethos of continuous improvement, we’re confident that with a few refinements we can pay out even more in 2024. After all, any money that goes toward building a better, more secure product is money well spent! We’d like to close by extending a special and heartfelt thank you to everyone who has contributed to our bug bounty program and discovered vulnerabilities – keep up the great work!


The post The Zabbix/HackerOne Bug Bounty Program: A Year of Results appeared first on Zabbix Blog.

Какъв механизъм за скрининг за рискови чуждестранни инвестиции приехме

Post Syndicated from Bozho original https://blog.bozho.net/blog/4230

Приехме закон за скрининг на рискови чуждестранни инвестиции. Тъй като той е много важен за инвестиционния климат, по него имаше процедурни особености – мина два пъти на второ четене в комисия, за да сме сигурни, че няма да създадем административни пречки пред чуждестранните инвестиции.

Със закона (който въвежда текстове в Закона за насърчаване на инвестициите) се предвижда задължение за разрешение от междуведомственя комисия за скрининг за пряка чуждестранна инвестиция в секторите, свързани със сигурността и обществения ред. Приемането на закона е задължение на България по европейския Регламент (ЕС) 2019/452, но регламентът дава възможност на държавите да го адаптират спрямо своите приротитети и нужди. Скринингът цели да ограничи т.нар. корозивен капитал – капитал с неясен произход, със спорна пазарна ориентация, мотивиран от екплоатирането на административни пропуски в държавата, където се осъществява инвестицията и придобиване на контрол върху стратегически обекти. Тези рискови инвестиции, според регламента на ЕС, трябва да бъдат подложени на скрининг.

Това, което успяхме да постигнем (от ППДБ) за облекчение на инвестиционния процес, са следните неща:

  • скринингът да е само, когато дейността на дружеството, в което се инвестира, е в обхвата на регламента – т.е. сигурност и обществен ред. По принцип това само по себе си може да бъде тълкувано разширително от администрацията, което налага и останалите мерки по-долу.
  • на скрининг да не се полдагат държави, които смятаме за нискорискови , като такива се определят по два начина – единият е със списък, предложен от Министерски съвет и одобрен от парламента, а другият е с конкретен списък в закона – САЩ, Обединеното кралство, Япония, Корея, Канада, Нова Зеландия, Австралия, ОАЕ и Саудитска Арабия. Дали последните две са нискорискови е дълга тема, но там потенцеиалните проблеми не са свързани с т.нар. „корозивен капитал“, а евентуално с други рискове за финансовата система, които скрининга не решава така или иначе. Има дискусия дали списъците с държави са в съответсвие с всички международни договори, по които България е страна, но предвид, че на европейско ниво текат процеси по надграждане и уеднаквяване на скрининговите механизми, нашата временна мярка е с цел защита на инвестиционния климат от излишна бюрокрация.
  • сделки, които все пак подлежат на скрининг, се ползват от мълчаливо съгласие при изтичане на 45-дневния срок за издаване на разрешение. Мълчаливото съгласие по принцип е общият ред за такъв тип разрешителни режими, съгласно Закона за ограничаване на административното регулиране и административния контрол върху стопанската дейност, но тук го записахме изрично, за да не влиза администрацията в тълкуване дали се прилага. Мълчаливите съгласия са индивидуални административни актове, т.е. имат силата на изрично разрешение. Има рискове, произтичащи от връчването на решенията за скрининг (т.е. ако решение е взето преди срока, но е комуникирано след срока), но те се елиминират при използване на Системата за сигурно електронно връчване, при която връчването се случва в реално време и гарантира датата и часа на изпращане и получаване.
  • скрининговият процес не спира производствата за други лицензи и разрешения – т.е. не може процедурата по скрининг да се използва от КЗК, КЕВР, КФН, КРС или някой друг държавен орган за спиране или забавяне на прозиводства по техните специални закони. А много от сделките в обхвата на регламента са регулирани от някой такъв регулатор.
  • държавата ще носи отговорност за вреди по нейна вина, т.е. ако напр. след мълчаливо съгласие отвори ад-хок скрининг и това навреди на инвеститора, той може да осъди държавата за причинените вреди.
  • гарантиране, че всички становище, вкл. на службите за сигурност, са мотивирани, за да няма бланкетни становища от типа „препоръчва да не разреши инвестицията, поради налична информация в Държавна агенция „Национална сигурност““. Съответно решенията на съвета трябва да са мотивирани и пропорционални, а не бланкетни и прекомерни. Това на пръв поглед са декларативни текстове, но дават повече сигурност, че при съдебен процес, той ще бъде в полза на инвеститора, в случай, че държавен орган направомерно е ограничил дадена инвестиция.
  • съветът за скрнинг ще публикува данни за получените заявления за скрининг и за това какви решения е взел. По този начин ще е възможно да се следи как се движи процесът по скрининг и дали той не е прекалено рестриктивен.

На задължителен скриниг подлежат инвестиции от Русия и Беларус, както и от компании, в които има 25% собственост на лица от тези държави. Руските капитали са най-корозивни, и когато става дума за национална сигурност в контекста на войната, е нужен специален ред за тях. За останалите трети страни се прилага изискването за контрол – т.е. 50%+1, пряко или непряко, вкл. чрез група лица, всяко от които под 50%.

Регламентът предвижда задължителен скрининг на т.нар. „критични технологии“, като изкуствен интелект, роботика, киберсигурност и др. В нашия закон има специфична разпоредба за високотехнологични компании в секторите, свързани със сигурност и обществен ред, като единствената разлика спрямо останалите инвестиции е в праговете за скрининг. Но високотехнологични инвестиции от нискорискови държави също не подлежат на скрининг, така че технологичната ни индустрия няма да има повишена административна тежест за привличане на капитал.

Законът не е е перфектен, но тъй като такъв тип закони се въвеждат в Европа за първи път, все още европейските държави, вкл. България, намират правилния баланс. Смятам, че ние намерихме добър баланс между гарантиране на националната сигурност чрез ограничаване на корозивен капитал и свободата на движението на капитали и свободния инвестиционен климат.

Материалът Какъв механизъм за скрининг за рискови чуждестранни инвестиции приехме е публикуван за пръв път на БЛОГодаря.

NVIDIA Blows-out Earnings as Over 83 Percent of Revenue From the AI Data Center Boom

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/nvidia-blows-out-earnings-as-over-83-percent-of-revenue-from-the-ai-data-center-boom/

NVIDIA is putting its gaming GPU company legacy to rest as the data center group is propelling the company on a wild growth trajectory

The post NVIDIA Blows-out Earnings as Over 83 Percent of Revenue From the AI Data Center Boom appeared first on ServeTheHome.

Simplify data streaming ingestion for analytics using Amazon MSK and Amazon Redshift

Post Syndicated from Sebastian Vlad original https://aws.amazon.com/blogs/big-data/simplify-data-streaming-ingestion-for-analytics-using-amazon-msk-and-amazon-redshift/

Towards the end of 2022, AWS announced the general availability of real-time streaming ingestion to Amazon Redshift for Amazon Kinesis Data Streams and Amazon Managed Streaming for Apache Kafka (Amazon MSK), eliminating the need to stage streaming data in Amazon Simple Storage Service (Amazon S3) before ingesting it into Amazon Redshift.

Streaming ingestion from Amazon MSK into Amazon Redshift, represents a cutting-edge approach to real-time data processing and analysis. Amazon MSK serves as a highly scalable, and fully managed service for Apache Kafka, allowing for seamless collection and processing of vast streams of data. Integrating streaming data into Amazon Redshift brings immense value by enabling organizations to harness the potential of real-time analytics and data-driven decision-making.

This integration enables you to achieve low latency, measured in seconds, while ingesting hundreds of megabytes of streaming data per second into Amazon Redshift. At the same time, this integration helps make sure that the most up-to-date information is readily available for analysis. Because the integration doesn’t require staging data in Amazon S3, Amazon Redshift can ingest streaming data at a lower latency and without intermediary storage cost.

You can configure Amazon Redshift streaming ingestion on a Redshift cluster using SQL statements to authenticate and connect to an MSK topic. This solution is an excellent option for data engineers that are looking to simplify data pipelines and reduce the operational cost.

In this post, we provide a complete overview on how to configure Amazon Redshift streaming ingestion from Amazon MSK.

Solution overview

The following architecture diagram describes the AWS services and features you will be using.

architecture diagram describing the AWS services and features you will be using

The workflow includes the following steps:

  1. You start with configuring an Amazon MSK Connect source connector, to create an MSK topic, generate mock data, and write it to the MSK topic. For this post, we work with mock customer data.
  2. The next step is to connect to a Redshift cluster using the Query Editor v2.
  3. Finally, you configure an external schema and create a materialized view in Amazon Redshift, to consume the data from the MSK topic. This solution does not rely on an MSK Connect sink connector to export the data from Amazon MSK to Amazon Redshift.

The following solution architecture diagram describes in more detail the configuration and integration of the AWS services you will be using.
solution architecture diagram describing in more detail the configuration and integration of the AWS services you will be using
The workflow includes the following steps:

  1. You deploy an MSK Connect source connector, an MSK cluster, and a Redshift cluster within the private subnets on a VPC.
  2. The MSK Connect source connector uses granular permissions defined in an AWS Identity and Access Management (IAM) in-line policy attached to an IAM role, which allows the source connector to perform actions on the MSK cluster.
  3. The MSK Connect source connector logs are captured and sent to an Amazon CloudWatch log group.
  4. The MSK cluster uses a custom MSK cluster configuration, allowing the MSK Connect connector to create topics on the MSK cluster.
  5. The MSK cluster logs are captured and sent to an Amazon CloudWatch log group.
  6. The Redshift cluster uses granular permissions defined in an IAM in-line policy attached to an IAM role, which allows the Redshift cluster to perform actions on the MSK cluster.
  7. You can use the Query Editor v2 to connect to the Redshift cluster.

Prerequisites

To simplify the provisioning and configuration of the prerequisite resources, you can use the following AWS CloudFormation template:

Complete the following steps when launching the stack:

  1. For Stack name, enter a meaningful name for the stack, for example, prerequisites.
  2. Choose Next.
  3. Choose Next.
  4. Select I acknowledge that AWS CloudFormation might create IAM resources with custom names.
  5. Choose Submit.

The CloudFormation stack creates the following resources:

  • A VPC custom-vpc, created across three Availability Zones, with three public subnets and three private subnets:
    • The public subnets are associated with a public route table, and outbound traffic is directed to an internet gateway.
    • The private subnets are associated with a private route table, and outbound traffic is sent to a NAT gateway.
  • An internet gateway attached to the Amazon VPC.
  • A NAT gateway that is associated with an elastic IP and is deployed in one of the public subnets.
  • Three security groups:
    • msk-connect-sg, which will be later associated with the MSK Connect connector.
    • redshift-sg, which will be later associated with the Redshift cluster.
    • msk-cluster-sg, which will be later associated with the MSK cluster. It allows inbound traffic from msk-connect-sg, and redshift-sg.
  • Two CloudWatch log groups:
    • msk-connect-logs, to be used for the MSK Connect logs.
    • msk-cluster-logs, to be used for the MSK cluster logs.
  • Two IAM Roles:
    • msk-connect-role, which includes granular IAM permissions for MSK Connect.
    • redshift-role, which includes granular IAM permissions for Amazon Redshift.
  • A custom MSK cluster configuration, allowing the MSK Connect connector to create topics on the MSK cluster.
  • An MSK cluster, with three brokers deployed across the three private subnets of custom-vpc. The msk-cluster-sg security group and the custom-msk-cluster-configuration configuration are applied to the MSK cluster. The broker logs are delivered to the msk-cluster-logs CloudWatch log group.
  • A Redshift cluster subnet group, which is using the three private subnets of custom-vpc.
  • A Redshift cluster, with one single node deployed in a private subnet within the Redshift cluster subnet group. The redshift-sg security group and redshift-role IAM role are applied to the Redshift cluster.

Create an MSK Connect custom plugin

For this post, we use an Amazon MSK data generator deployed in MSK Connect, to generate mock customer data, and write it to an MSK topic.

Complete the following steps:

  1. Download the Amazon MSK data generator JAR file with dependencies from GitHub.
    awslabs github page for downloading the jar file of the amazon msk data generator
  2. Upload the JAR file into an S3 bucket in your AWS account.
    amazon s3 console image showing the uploaded jar file in an s3 bucket
  3. On the Amazon MSK console, choose Custom plugins under MSK Connect in the navigation pane.
  4. Choose Create custom plugin.
  5. Choose Browse S3, search for the Amazon MSK data generator JAR file you uploaded to Amazon S3, then choose Choose.
  6. For Custom plugin name, enter msk-datagen-plugin.
  7. Choose Create custom plugin.

When the custom plugin is created, you will see that its status is Active, and you can move to the next step.
amazon msk console showing the msk connect custom plugin being successfully created

Create an MSK Connect connector

Complete the following steps to create your connector:

  1. On the Amazon MSK console, choose Connectors under MSK Connect in the navigation pane.
  2. Choose Create connector.
  3. For Custom plugin type, choose Use existing plugin.
  4. Select msk-datagen-plugin, then choose Next.
  5. For Connector name, enter msk-datagen-connector.
  6. For Cluster type, choose Self-managed Apache Kafka cluster.
  7. For VPC, choose custom-vpc.
  8. For Subnet 1, choose the private subnet within your first Availability Zone.

For the custom-vpc created by the CloudFormation template, we are using odd CIDR ranges for public subnets, and even CIDR ranges for the private subnets:

    • The CIDRs for the public subnets are 10.10.1.0/24, 10.10.3.0/24, and 10.10.5.0/24
    • The CIDRs for the private subnets are 10.10.2.0/24, 10.10.4.0/24, and 10.10.6.0/24
  1. For Subnet 2, select the private subnet within your second Availability Zone.
  2. For Subnet 3, select the private subnet within your third Availability Zone.
  3. For Bootstrap servers, enter the list of bootstrap servers for TLS authentication of your MSK cluster.

To retrieve the bootstrap servers for your MSK cluster, navigate to the Amazon MSK console, choose Clusters, choose msk-cluster, then choose View client information. Copy the TLS values for the bootstrap servers.

  1. For Security groups, choose Use specific security groups with access to this cluster, and choose msk-connect-sg.
  2. For Connector configuration, replace the default settings with the following:
connector.class=com.amazonaws.mskdatagen.GeneratorSourceConnector
tasks.max=2
genkp.customer.with=#{Code.isbn10}
genv.customer.name.with=#{Name.full_name}
genv.customer.gender.with=#{Demographic.sex}
genv.customer.favorite_beer.with=#{Beer.name}
genv.customer.state.with=#{Address.state}
genkp.order.with=#{Code.isbn10}
genv.order.product_id.with=#{number.number_between '101','109'}
genv.order.quantity.with=#{number.number_between '1','5'}
genv.order.customer_id.matching=customer.key
global.throttle.ms=2000
global.history.records.max=1000
value.converter=org.apache.kafka.connect.json.JsonConverter
value.converter.schemas.enable=false
  1. For Connector capacity, choose Provisioned.
  2. For MCU count per worker, choose 1.
  3. For Number of workers, choose 1.
  4. For Worker configuration, choose Use the MSK default configuration.
  5. For Access permissions, choose msk-connect-role.
  6. Choose Next.
  7. For Encryption, select TLS encrypted traffic.
  8. Choose Next.
  9. For Log delivery, choose Deliver to Amazon CloudWatch Logs.
  10. Choose Browse, select msk-connect-logs, and choose Choose.
  11. Choose Next.
  12. Review and choose Create connector.

After the custom connector is created, you will see that its status is Running, and you can move to the next step.
amazon msk console showing the msk connect connector being successfully created

Configure Amazon Redshift streaming ingestion for Amazon MSK

Complete the following steps to set up streaming ingestion:

  1. Connect to your Redshift cluster using Query Editor v2, and authenticate with the database user name awsuser, and password Awsuser123.
  2. Create an external schema from Amazon MSK using the following SQL statement.

In the following code, enter the values for the redshift-role IAM role, and the msk-cluster cluster ARN.

CREATE EXTERNAL SCHEMA msk_external_schema
FROM MSK
IAM_ROLE '<insert your redshift-role arn>'
AUTHENTICATION iam
CLUSTER_ARN '<insert your msk-cluster arn>';
  1. Choose Run to run the SQL statement.

redshift query editor v2 showing the SQL statement used to create an external schema from amazon msk

  1. Create a materialized view using the following SQL statement:
CREATE MATERIALIZED VIEW msk_mview AUTO REFRESH YES AS
SELECT
    "kafka_partition",
    "kafka_offset",
    "kafka_timestamp_type",
    "kafka_timestamp",
    "kafka_key",
    JSON_PARSE(kafka_value) as Data,
    "kafka_headers"
FROM
    "dev"."msk_external_schema"."customer"
  1. Choose Run to run the SQL statement.

redshift query editor v2 showing the SQL statement used to create a materialized view

  1. You can now query the materialized view using the following SQL statement:
select * from msk_mview LIMIT 100;
  1. Choose Run to run the SQL statement.

redshift query editor v2 showing the SQL statement used to query the materialized view

  1. To monitor the progress of records loaded via streaming ingestion, you can take advantage of the SYS_STREAM_SCAN_STATES monitoring view using the following SQL statement:
select * from SYS_STREAM_SCAN_STATES;
  1. Choose Run to run the SQL statement.

redshift query editor v2 showing the SQL statement used to query the sys stream scan states monitoring view

  1. To monitor errors encountered on records loaded via streaming ingestion, you can take advantage of the SYS_STREAM_SCAN_ERRORS monitoring view using the following SQL statement:
select * from SYS_STREAM_SCAN_ERRORS;
  1. Choose Run to run the SQL statement.redshift query editor v2 showing the SQL statement used to query the sys stream scan errors monitoring view

Clean up

After following along, if you no longer need the resources you created, delete them in the following order to prevent incurring additional charges:

  1. Delete the MSK Connect connector msk-datagen-connector.
  2. Delete the MSK Connect plugin msk-datagen-plugin.
  3. Delete the Amazon MSK data generator JAR file you downloaded, and delete the S3 bucket you created.
  4. After you delete your MSK Connect connector, you can delete the CloudFormation template. All the resources created by the CloudFormation template will be automatically deleted from your AWS account.

Conclusion

In this post, we demonstrated how to configure Amazon Redshift streaming ingestion from Amazon MSK, with a focus on privacy and security.

The combination of the ability of Amazon MSK to handle high throughput data streams with the robust analytical capabilities of Amazon Redshift empowers business to derive actionable insights promptly. This real-time data integration enhances the agility and responsiveness of organizations in understanding changing data trends, customer behaviors, and operational patterns. It allows for timely and informed decision-making, thereby gaining a competitive edge in today’s dynamic business landscape.

This solution is also applicable for customers that are looking to use Amazon MSK Serverless and Amazon Redshift Serverless.

We hope this post was a good opportunity to learn more about AWS service integration and configuration. Let us know your feedback in the comments section.


About the authors

Sebastian Vlad is a Senior Partner Solutions Architect with Amazon Web Services, with a passion for data and analytics solutions and customer success. Sebastian works with enterprise customers to help them design and build modern, secure, and scalable solutions to achieve their business outcomes.

Sharad Pai is a Lead Technical Consultant at AWS. He specializes in streaming analytics and helps customers build scalable solutions using Amazon MSK and Amazon Kinesis. He has over 16 years of industry experience and is currently working with media customers who are hosting live streaming platforms on AWS, managing peak concurrency of over 50 million. Prior to joining AWS, Sharad’s career as a lead software developer included 9 years of coding, working with open source technologies like JavaScript, Python, and PHP.

[$] Sudo and its alternatives

Post Syndicated from jake original https://lwn.net/Articles/962588/

Sudo is a ubiquitous tool for running
commands
with the privileges of another user on Unix-like operating systems. Over
the past decade or so,
some alternatives have
been developed; the base system of OpenBSD now comes with doas instead, sudo-rs is a subset of
sudo reimplemented in Rust, and, somewhat surprisingly, Microsoft also
recently announced
its own Sudo for Windows. Each of these offers a different approach to the
task of providing limited privileges to unprivileged users.

Combine AWS Glue and Amazon MWAA to build advanced VPC selection and failover strategies

Post Syndicated from Michael Greenshtein original https://aws.amazon.com/blogs/big-data/combine-aws-glue-and-amazon-mwaa-to-build-advanced-vpc-selection-and-failover-strategies/

AWS Glue is a serverless data integration service that makes it straightforward to discover, prepare, move, and integrate data from multiple sources for analytics, machine learning (ML), and application development.

AWS Glue customers often have to meet strict security requirements, which sometimes involve locking down the network connectivity allowed to the job, or running inside a specific VPC to access another service. To run inside the VPC, the jobs needs to be assigned to a single subnet, but the most suitable subnet can change over time (for instance, based on the usage and availability), so you may prefer to make that decision at runtime, based on your own strategy.

Amazon Managed Workflows for Apache Airflow (Amazon MWAA) is an AWS service to run managed Airflow workflows, which allow writing custom logic to coordinate how tasks such as AWS Glue jobs run.

In this post, we show how to run an AWS Glue job as part of an Airflow workflow, with dynamic configurable selection of the VPC subnet assigned to the job at runtime.

Solution overview

To run inside a VPC, an AWS Glue job needs to be assigned at least a connection that includes network configuration. Any connection allows specifying a VPC, subnet, and security group, but for simplicity, this post uses connections of type: NETWORK, which just defines the network configuration and doesn’t involve external systems.

If the job has a fixed subnet assigned by a single connection, in case of a service outage on the Availability Zones or if the subnet isn’t available for other reasons, the job can’t run. Furthermore, each node (driver or worker) in an AWS Glue job requires an IP address assigned from the subnet. When running many large jobs concurrently, this could lead to an IP address shortage and the job running with fewer nodes than intended or not running at all.

AWS Glue extract, transform, and load (ETL) jobs allow multiple connections to be specified with multiple network configurations. However, the job will always try to use the connections’ network configuration in the order listed and pick the first one that passes the health checks and has at least two IP addresses to get the job started, which might not be the optimal option.

With this solution, you can enhance and customize that behavior by reordering the connections dynamically and defining the selection priority. If a retry is needed, the connections are reprioritized again based on the strategy, because the conditions might have changed since the last run.

As a result, it helps prevent the job from failing to run or running under capacity due to subnet IP address shortage or even an outage, while meeting the network security and connectivity requirements.

The following diagram illustrates the solution architecture.

Prerequisites

To follow the steps of the post, you need a user that can log in to the AWS Management Console and has permission to access Amazon MWAA, Amazon Virtual Private Cloud (Amazon VPC), and AWS Glue. The AWS Region where you choose to deploy the solution needs the capacity to create a VPC and two elastic IP addresses. The default Regional quota for both types of resources is five, so you might need to request an increase via the console.

You also need an AWS Identity and Access Management (IAM) role suitable to run AWS Glue jobs if you don’t have one already. For instructions, refer to Create an IAM role for AWS Glue.

Deploy an Airflow environment and VPC

First, you’ll deploy a new Airflow environment, including the creation of a new VPC with two public subnets and two private ones. This is because Amazon MWAA requires Availability Zone failure tolerance, so it needs to run on two subnets on two different Availability Zones in the Region. The public subnets are used so the NAT Gateway can provide internet access for the private subnets.

Complete the following steps:

  1. Create an AWS CloudFormation template in your computer by copying the template from the following quick start guide into a local text file.
  2. On the AWS CloudFormation console, choose Stacks in the navigation pane.
  3. Choose Create stack with the option With new resources (standard).
  4. Choose Upload a template file and choose the local template file.
  5. Choose Next.
  6. Complete the setup steps, entering a name for the environment, and leave the rest of the parameters as default.
  7. On the last step, acknowledge that resources will be created and choose Submit.

The creation can take 20–30 minutes, until the status of the stack changes to CREATE_COMPLETE.

The resource that will take most of time is the Airflow environment. While it’s being created, you can continue with the following steps, until you are required to open the Airflow UI.

  1. On the stack’s Resources tab, note the IDs for the VPC and two private subnets (PrivateSubnet1 and PrivateSubnet2), to use in the next step.

Create AWS Glue connections

The CloudFormation template deploys two private subnets. In this step, you create an AWS Glue connection to each one so AWS Glue jobs can run in them. Amazon MWAA recently added the capacity to run the Airflow cluster on shared VPCs, which reduces cost and simplifies network management. For more information, refer to Introducing shared VPC support on Amazon MWAA.

Complete the following steps to create the connections:

  1. On the AWS Glue console, choose Data connections in the navigation pane.
  2. Choose Create connection.
  3. Choose Network as the data source.
  4. Choose the VPC and private subnet (PrivateSubnet1) created by the CloudFormation stack.
  5. Use the default security group.
  6. Choose Next.
  7. For the connection name, enter MWAA-Glue-Blog-Subnet1.
  8. Review the details and complete the creation.
  9. Repeat these steps using PrivateSubnet2 and name the connection MWAA-Glue-Blog-Subnet2.

Create the AWS Glue job

Now you create the AWS Glue job that will be triggered later by the Airflow workflow. The job uses the connections created in the previous section, but instead of assigning them directly on the job, as you would normally do, in this scenario you leave the job connections list empty and let the workflow decide which one to use at runtime.

The job script in this case is not significant and is just intended to demonstrate the job ran in one of the subnets, depending on the connection.

  1. On the AWS Glue console, choose ETL jobs in the navigation pane, then choose Script editor.
  2. Leave the default options (Spark engine and Start fresh) and choose Create script.
  3. Replace the placeholder script with the following Python code:
    import ipaddress
    import socket
    
    subnets = {
        "PrivateSubnet1": "10.192.20.0/24",
        "PrivateSubnet2": "10.192.21.0/24"
    }
    
    ip = socket.gethostbyname(socket.gethostname())
    subnet_name = "unknown"
    for subnet, cidr in subnets.items():
        if ipaddress.ip_address(ip) in ipaddress.ip_network(cidr):
            subnet_name = subnet
    
    print(f"The driver node has been assigned the ip: {ip}"
          + f" which belongs to the subnet: {subnet_name}")
    

  4. Rename the job to AirflowBlogJob.
  5. On the Job details tab, for IAM Role, choose any role and enter 2 for the number of workers (just for frugality).
  6. Save these changes so the job is created.

Grant AWS Glue permissions to the Airflow environment role

The role created for Airflow by the CloudFormation template provides the basic permissions to run workflows but not to interact with other services such as AWS Glue. In a production project, you would define your own templates with these additional permissions, but in this post, for simplicity, you add the additional permissions as an inline policy. Complete the following steps:

  1. On the IAM console, choose Roles in the navigation pane.
  2. Locate the role created by the template; it will start with the name you assigned to the CloudFormation stack and then -MwaaExecutionRole-.
  3. On the role details page, on the Add permissions menu, choose Create inline policy.
  4. Switch from Visual to JSON mode and enter the following JSON on the textbox. It assumes that the AWS Glue role you have follows the convention of starting with AWSGlueServiceRole. For enhanced security, you can replace the wildcard resource on the ec2:DescribeSubnets permission with the ARNs of the two private subnets from the CloudFormation stack.
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "glue:GetConnection"
                ],
                "Resource": [
                    "arn:aws:glue:*:*:connection/MWAA-Glue-Blog-Subnet*",
                    "arn:aws:glue:*:*:catalog"
                ]
            },
            {
                "Effect": "Allow",
                "Action": [
                    "glue:UpdateJob",
                    "glue:GetJob",
                    "glue:StartJobRun",
                    "glue:GetJobRun"
                ],
                "Resource": [
                    "arn:aws:glue:*:*:job/AirflowBlogJob",
                    "arn:aws:glue:*:*:job/BlogAirflow"
                ]
            },
            {
                "Effect": "Allow",
                "Action": [
                    "ec2:DescribeSubnets"
                ],
                "Resource": "*"
            },
            {
                "Effect": "Allow",
                "Action": [
                    "iam:GetRole",
                    "iam:PassRole"
                ],
                "Resource": "arn:aws:iam::*:role/service-role/AWSGlueServiceRole*"
            }
        ]
    }
    

  5. Choose Next.
  6. Enter GlueRelatedPermissions as the policy name and complete the creation.

In this example, we use an ETL script job; for a visual job, because it generates the script automatically on save, the Airflow role would need permission to write to the configured script path on Amazon Simple Storage Service (Amazon S3).

Create the Airflow DAG

An Airflow workflow is based on a Directed Acyclic Graph (DAG), which is defined by a Python file that programmatically specifies the different tasks involved and its interdependencies. Complete the following scripts to create the DAG:

  1. Create a local file named glue_job_dag.py using a text editor.

In each of the following steps, we provide a code snippet to enter into the file and an explanation of what is does.

  1. The following snippet adds the required Python modules imports. The modules are already installed on Airflow; if that weren’t the case, you would need to use a requirements.txt file to indicate to Airflow which modules to install. It also defines the Boto3 clients that the code will use later. By default, they will use the same role and Region as Airflow, that’s why you set up before the role with the additional permissions required.
    import boto3
    from pendulum import datetime, duration
    from random import shuffle
    from airflow import DAG
    from airflow.decorators import dag, task
    from airflow.models import Variable
    from airflow.providers.amazon.aws.operators.glue import GlueJobOperator
    
    glue_client = boto3.client('glue')
    ec2 = boto3.client('ec2')
    

  2. The following snippet adds three functions to implement the connection order strategy, which defines how to reorder the connections given to establish their priority. This is just an example; you can build your custom code to implement your own logic, as per your needs. The code first checks the IPs available on each connection subnet and separates the ones that have enough IPs available to run the job at full capacity and those that could be used because they have at least two IPs available, which is the minimum a job needs to start. If the strategy is set to random, it will randomize the order within each of the connection groups previously described and add any other connections. If the strategy is capacity, it will order them from most IPs free to fewest.
    def get_available_ips_from_connection(glue_connection_name):
        conn_response = glue_client.get_connection(Name=glue_connection_name)
        connection_properties = conn_response['Connection']['PhysicalConnectionRequirements']
        subnet_id = connection_properties['SubnetId']
        subnet_response = ec2.describe_subnets(SubnetIds=[subnet_id])
        return subnet_response['Subnets'][0]['AvailableIpAddressCount']
    
    def get_connections_free_ips(glue_connection_names, num_workers):
        good_connections = []
        usable_connections = []    
        for connection_name in glue_connection_names:
            try:
                available_ips = get_available_ips_from_connection(connection_name)
                # Priority to connections that can hold the full cluster and we haven't just tried
                if available_ips >= num_workers:
                    good_connections.append((connection_name, available_ips))
                elif available_ips >= 2: # The bare minimum to start a Glue job
                    usable_connections.append((connection_name, available_ips))                
            except Exception as e:
                print(f"[WARNING] Failed to check the free ips for:{connection_name}, will skip. Exception: {e}")  
        return good_connections, usable_connections
    
    def prioritize_connections(connection_list, num_workers, strategy):
        (good_connections, usable_connections) = get_connections_free_ips(connection_list, num_workers)
        print(f"Good connections: {good_connections}")
        print(f"Usable connections: {usable_connections}")
        all_conn = []
        if strategy=="random":
            shuffle(good_connections)
            shuffle(usable_connections)
            # Good connections have priority
            all_conn = good_connections + usable_connections
        elif strategy=="capacity":
            # We can sort both at the same time
            all_conn = good_connections + usable_connections
            all_conn.sort(key=lambda x: -x[1])
        else: 
            raise ValueError(f"Unknown strategy specified: {strategy}")    
        result = [c[0] for c in all_conn] # Just need the name
        # Keep at the end any other connections that could not be checked for ips
        result += [c for c in connection_list if c not in result]
        return result
    

  3. The following code creates the DAG itself with the run job task, which updates the job with the connection order defined by the strategy, runs it, and waits for the results. The job name, connections, and strategy come from Airflow variables, so it can be easily configured and updated. It has two retries with exponential backoff configured, so if the tasks fails, it will repeat the full task including the connection selection. Maybe now the best choice is another connection, or the subnet previously picked randomly is in an Availability Zone that is currently suffering an outage, and by picking a different one, it can recover.
    with DAG(
        dag_id='glue_job_dag',
        schedule_interval=None, # Run on demand only
        start_date=datetime(2000, 1, 1), # A start date is required
        max_active_runs=1,
        catchup=False
    ) as glue_dag:
        
        @task(
            task_id="glue_task", 
            retries=2,
            retry_delay=duration(seconds = 30),
            retry_exponential_backoff=True
        )
        def run_job_task(**ctx):    
            glue_connections = Variable.get("glue_job_dag.glue_connections").strip().split(',')
            glue_jobname = Variable.get("glue_job_dag.glue_job_name").strip()
            strategy= Variable.get('glue_job_dag.strategy', 'random') # random or capacity
            print(f"Connections available: {glue_connections}")
            print(f"Glue job name: {glue_jobname}")
            print(f"Strategy to use: {strategy}")
            job_props = glue_client.get_job(JobName=glue_jobname)['Job']            
            num_workers = job_props['NumberOfWorkers']
            
            glue_connections = prioritize_connections(glue_connections, num_workers, strategy)
            print(f"Running Glue job with the connection order: {glue_connections}")
            existing_connections = job_props.get('Connections',{}).get('Connections', [])
            # Preserve other connections that we don't manage
            other_connections = [con for con in existing_connections if con not in glue_connections]
            job_props['Connections'] = {"Connections": glue_connections + other_connections}
            # Clean up properties so we can reuse the dict for the update request
            for prop_name in ['Name', 'CreatedOn', 'LastModifiedOn', 'AllocatedCapacity', 'MaxCapacity']:
                del job_props[prop_name]
    
            GlueJobOperator(
                task_id='submit_job',
                job_name=glue_jobname,
                iam_role_name=job_props['Role'].split('/')[-1],
                update_config=True,
                create_job_kwargs=job_props,
                wait_for_completion=True
            ).execute(ctx)   
            
        run_job_task()
    

Create the Airflow workflow

Now you create a workflow that invokes the AWS Glue job you just created:

  1. On the Amazon S3 console, locate the bucket created by the CloudFormation template, which will have a name starting with the name of the stack and then -environmentbucket- (for example, myairflowstack-environmentbucket-ap1qks3nvvr4).
  2. Inside that bucket, create a folder called dags, and inside that folder, upload the DAG file glue_job_dag.py that you created in the previous section.
  3. On the Amazon MWAA console, navigate to the environment you deployed with the CloudFormation stack.

If the status is not yet Available, wait until it reaches that state. It shouldn’t take longer than 30 minutes since you deployed the CloudFormation stack.

  1. Choose the environment link on the table to see the environment details.

It’s configured to pick up DAGs from the bucket and folder you used in the previous steps. Airflow will monitor that folder for changes.

  1. Choose Open Airflow UI to open a new tab accessing the Airflow UI, using the integrated IAM security to log you in.

If there’s any issue with the DAG file you created, it will display an error on top of the page indicating the lines affected. In that case, review the steps and upload again. After a few seconds, it will parse it and update or remove the error banner.

  1. On the Admin menu, choose Variables.
  2. Add three variables with the following keys and values:
    1. Key glue_job_dag.glue_connections with value MWAA-Glue-Blog-Subnet1,MWAA-Glue-Blog-Subnet2.
    2. Key glue_job_dag.glue_job_name with value AirflowBlogJob.
    3. Key glue_job_dag.strategy with value capacity.

Run the job with a dynamic subnet assignment

Now you’re ready to run the workflow and see the strategy dynamically reordering the connections.

  1. On the Airflow UI, choose DAGs, and on the row glue_job_dag, choose the play icon.
  2. On the Browse menu, choose Task instances.
  3. On the instances table, scroll right to display the Log Url and choose the icon on it to open the log.

The log will update as the task runs; you can locate the line starting with “Running Glue job with the connection order:” and the previous lines showing details of the connection IPs and the category assigned. If an error occurs, you’ll see the details in this log.

  1. On the AWS Glue console, choose ETL jobs in the navigation pane, then choose the job AirflowBlogJob.
  2. On the Runs tab, choose the run instance, then the Output logs link, which will open a new tab.
  3. On the new tab, use the log stream link to open it.

It will display the IP that the driver was assigned and which subnet it belongs to, which should match the connection indicated by Airflow (if the log is not displayed, choose Resume so it gets updated as soon as it’s available).

  1. On the Airflow UI, edit the Airflow variable glue_job_dag.strategy to set it to random.
  2. Run the DAG multiple times and see how the ordering changes.

Clean up

If you no longer need the deployment, delete the resources to avoid any further charges:

  1. Delete the Python script you uploaded, so the S3 bucket can be automatically deleted in the next step.
  2. Delete the CloudFormation stack.
  3. Delete the AWS Glue job.
  4. Delete the script that the job saved in Amazon S3.
  5. Delete the connections you created as part of this post.

Conclusion

In this post, we showed how AWS Glue and Amazon MWAA can work together to build more advanced custom workflows, while minimizing the operational and management overhead. This solution gives you more control about how your AWS Glue job runs to meet special operational, network, or security requirements.

You can deploy your own Amazon MWAA environment in multiple ways, such as with the template used in this post, on the Amazon MWAA console, or using the AWS CLI. You can also implement your own strategies to orchestrate AWS Glue jobs, based on your network architecture and requirements (for instance, to run the job closer to the data when possible).


About the authors

Michael Greenshtein is an Analytics Specialist Solutions Architect for the Public Sector.

Gonzalo Herreros is a Senior Big Data Architect on the AWS Glue team.
Your AI Toolbox: 16 Must Have Products

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/your-ai-toolbox-16-must-have-products/

A decorative image showing a chip networked to several tech icon images, including a computer and a cloud, with a box that says AI above the image.

Folks, it’s an understatement to say that the explosion of AI has been a wild ride. And, like any new, high-impact technology, the market initially floods with new companies. The normal lifecycle, of course, is that money is invested, companies are built, and then there will be winners and losers as the market narrows. Exciting times. 

That said, we thought it was a good time to take you back to the practical side of things. One of the most pressing questions these days is how businesses may want to use AI in their existing or future processes, what options exist, and which strategies and tools are likely to survive long term. 

We can’t predict who will sink or swim in the AI race—we might be able to help folks predict drive failure, but the Backblaze Crystal Ball (™) is not on our roadmap—so let’s talk about what we know. Things will change over time, and some of the tools we’ve included on this list will likely go away. And, as we fully expect all of you to have strong opinions, let us know what you’re using, which tools we may have missed, and why we’re wrong in the comments section.

Tools Businesses Can Implement Today (and the Problems They Solve)

As AI has become more accessible, we’ve seen it touted as either standalone tools or incorporated into existing software. It’s probably easiest to think about them in terms of the problems they solve, so here is a non-inclusive list.

The Large Language Model (LLM) “Everything Bot”

LLMs are useful in generative AI tasks because they work largely on a model of association. They intake huge amounts of data, use that to learn associations between ideas and words, and then use those learnings to perform tasks like creating copy or natural language search. That makes them great for a generalized use case (an “everything bot”) but it’s important to note that it’s not the only—or best—model for all AI/ML tasks. 

These generative AI models are designed to be talked to in whatever way suits the querier best, and are generally accessed via browser. That’s not to say that the models behind them aren’t being incorporated elsewhere in things like chat bots or search, but that they stand alone and can be identified easily. 

ChatGPT

In many ways, ChatGPT is the tool that broke the dam. It’s a large language model (LLM) whose multi-faceted capabilities were easily apparent and translatable across both business and consumer markets. Never say it came from nowhere, however: OpenAI and Microsoft Azure have been in cahoots for years creating the tool that (ahem) broke the internet. 

Google Gemini, née Google Bard

It’s undeniable that Google has been on the front lines of AI/ML for quite some time. Some experts even say that their networks are the best poised to build a sustainable AI architecture. So why is OpenAI’s ChatGPT the tool on everyone’s mind? Simply put, Google has had difficulty commercializing their AI product—until, that is, they announced Google Gemini, and folks took notice. Google Gemini represents a strong contender for the type of function that we all enjoy from ChatGPT, powered by all the infrastructure and research they’re already known for.

Machine Learning (ML)

ML tasks cover a wide range of possibilities. When you’re looking to build an algorithm yourself, however, you don’t have to start from ground zero. There are robust, open source communities that offer pre-trained models, community support, integration with cloud storage, access to large datasets, and more. 

  • TensorFlow: TensorFlow was originally developed by Google for internal research and production. It supports various programming languages like C++, Python, and Java, and is designed to scale easily from research to development.  
  • PyTorch: PyTorch, on the other hand, is built for rapid prototyping and experimentation, and is primarily built for Python. That makes the learning curve for most devs much shorter, and lots of folks will layer it with Keras for additional API support (without sacrificing the speed and lower-level control of PyTorch). 

Given the amount of flexibility in having an open source library, you see all sorts of things being built. A photo management company might grab a facial recognition algorithm, for instance, or use another to help order the parameters and hyperparameters of the algorithm. Think of it like wanting to build a table, but making the hammer and nails instead of purchasing your own. 

Building Products With AI

You may also want or need to invest more resources—maybe you want to add AI to your existing product. In that scenario, you might hire an AI consultant to help you design, build, and train the algorithm, buy processing power from CoreWeave or Google, and store your data on-premises or in cloud storage.

In reality, most companies will likely do a mix of things depending on how they operate and what they offer. The biggest thing I’m trying to get at by presenting these scenarios, however, is that most people likely won’t set up their own large scale infrastructure, instead relying on inference tools. And, there’s something of a distinction to be made between whether you’re using tools designed to create efficiencies in your business versus whether you’re creating or incorporating AI/ML into your products.

Data Analytics

Without being too contentions, data analytics is one of the most powerful applications of AI/ML. While we measly humans may still need to provide context to make sense of the identified patterns, computers are excellent at identifying them more quickly and accurately than we could ever dream. If you’re looking to crunch serious numbers, these two tools will come in handy.

  • Snowflake: Snowflake is a cloud-based data as a service (DaaS) company that specializes in data warehouses, data lakes, and data analytics. They provide a flexible, integration-friendly platform with options for both developing your own data tools or using built-out options. Loved by devs and business leaders alike, Snowflake is a powerhouse platform that supports big names and diverse customers such as AT&T, Netflix, Capital One, Canva, and Bumble. 
  • Looker: Looker is a business intelligence (BI) platform powered by Google. It’s a good example of a platform that takes the core functionalities of a product we’re already used to and layering on AI to make them more powerful. So, while BI platforms have long had robust data management and visualization capabilities, they can now do things like use natural language search or get automated data insights.

Development and Security

It’s no secret that one of the biggest pain points in the world of tech is having enough developers and having enough high quality ones, at that. It’s pushed the tech industry to work internationally, driven the creation of coding schools that train folks within six months, and compelled people to come up with codeless or low-code platforms that users of different skill levels can use. This also makes it one of the prime opportunities for the assistance of AI. 

  • GitHub Copilot: Even if you’re not in tech or working as a developer, you’ve likely heard of GitHub. Started in 2007 and officially launched in 2008, it’s a bit hard to imagine coding before it existed as the de facto center to find, share, and collaborate on code in a public forum. Now, they’re responsible for GitHub Copilot, which allows devs to generate code with a simple query. As with all generative tools, however, users should double check for accuracy and bias, and make sure to consider privacy, legal, and ethical concerns while using the tool. 

Customer Experience and Marketing

Customer relationship management (CRM) tools assist businesses in effectively communicating with their customers and audiences. You use them to glean insights as broadly as trends in how you’re finding and converting leads to customers, or as granular as a single users’ interactions with marketing emails. A well-honed CRM means being able to serve your target and existing customers effectively. 

  • Hubspot and Salesforce Einstein: Two of the largest CRM platforms on the market, these tools are designed to make everything from email to marketing emails to lead scoring to customer service interactions easy. AI has started popping up in almost every function offered, including social media post generation, support ticket routing, website personalization suggestions, and more.    

Operations, Productivity, and Efficiency

These kinds of tools take onerous everyday tasks and make them easy. Internally, these kinds of tools can represent massive savings to your OpEx budget, letting you use your resources more effectively. And, given that some of them also make processes external to your org easier (like scheduling meetings with new leads), they can also contribute to new and ongoing revenue streams. 

  • Loom: Loom is a specialized tool designed to make screen recording and subsequent video editing easy. Given how much time it takes to make video content, Loom’s targeting of this once-difficult task has certainly saved time and increased collaboration. Loom includes things like filler word and silence removal, auto-generating chapters with timestamps, summarizing the video, and so on. All features are designed for easy sharing and ingesting of data across video and text mediums.  
  • Calendly: Speaking of collaboration, remember how many emails it used to take to schedule a meeting, particularly if the person was external to your company? How about when you were working a conference and wanted to give a new lead an easy way to get on your calendar? And, of course, there’s the joy of managing multiple inboxes. (Thanks, Calendly. You changed my life.) Moving into the AI future, Calendly is doing similar small but mighty things: predicting your availability, detecting time zones, automating meeting schedules based on team member availability or round robin scheduling, cancellation insights, and more.  
  • Slack: Ah, Slack. Business experts have been trying for years to summarize the effect it’s had on workplace communication, and while it’s not the only tool on the market, it’s definitely a leader. Slack has been adding a variety of AI functions to its platform, including the ability to summarize channels, organize unreads, search and summarize messages—and then there’s all the work they’re doing with integrations rumored to be on the horizon, like creating meeting invite suggestions purely based on your mentioning “putting time on the calendar” in a message. 

Creative and Design 

Like coding and developer tools, creative of all kinds—image, video, copy—has long been a resource intensive task. These skills are not traditionally suited to corporate structures, and measuring whether one brand or another is better or worse is a complex process, though absolutely measurable and important. Generative AI, again like above, is giving teams the ability to create first drafts, or even train libraries, and then move the human oversight to a higher, more skilled, tier of work. 

  • Adobe and Figma: Both Adobe and Figma are reputable design collaboration tools. Though a merger was recently called off by both sides, both are incorporating AI to make it much, much easier to create images and video for all sorts of purposes. Generative AI means that large swaths of canvas can be filled by a generative tool that predicts background, for instance, or add stock versions of things like buildings with enough believability to fool a discerning eye. Video tools are still in beta, but early releases are impressive, to say the least. With the preview of OpenAI’s text-to-video model Sora making waves to the tune of a 7% drop in Adobe’s stock, video is the space to watch at the moment.
  • Jasper and Copy.ai: Just like image generation above, these bots are also creating usable copy for tasks of all kinds. And, just like all generative tools, AI copywriters deliver a baseline level of quality best suited to some human oversight. As time goes on, how much oversight remains to be seen.

Tools for Today; Build for Tomorrow

At the end of this roundup, it’s worth noting that there are plenty of tools on the market, and we’ve just presented a few of the bigger names. Honestly, we had trouble narrowing the field of what to include so to speak—this very easily could have been a much longer article, or even a series of articles that delved into things we’re seeing within each use case. As we talked about in AI 101: Do the Dollars Make Sense? (and as you can clearly see here), there’s a great diversity of use cases, technological demands, and unexplored potential in the AI space—which means that companies have a variety of strategic options when deciding how to implement AI or machine learning.

Most businesses will find it easier and more in line with their business goals to adopt software as a service (SaaS) solutions that are either sold as a whole package or integrated into existing tools. These types of tools are great because they’re almost plug and play—you can skip training the model and go straight to using them for whatever task you need. 

But, when you’re a hyperscaler and you’re talking about building infrastructure to support the processing and storage demands of the AI future, it’s a different scenario than when other types of businesses are talking about using or building an AI tool or algorithm specific to your business’ internal strategy or products. We’ve already seen that hyperscalers are going for broke in building data centers and processing hubs, investing in companies that are taking on different parts of the tech stack, and, of course, doing longer-term research and experimentation as well.

So, with a brave new world at our fingertips—being built as we’re interacting with it—the best thing for businesses to remember is that periods of rapid change offer opportunity, as long as you’re thoughtful about implementation. And, there are plenty of companies creating tools that make it easy to do just that. 

The post Your AI Toolbox: 16 Must Have Products appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

The collective thoughts of the interwebz