Tag Archives: AI

How AI is transforming analytics at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/how-ai-is-transforming-analytics

Introduction

At Grab, analytics sits close to almost every decision that matters. Our north star is the democratisation of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.

Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and developing insights for business opportunities, designing experiments and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.

As autonomy climbs, an analyst’s impact moves from producing the artefact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.

The ladder

We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgement stays for every analytics loop.

One distinction runs across every level: who owns the loop, and where human judgement is required.

Level What Human role Agent role
L2 AI-Assisted Owns and executes every step; uses AI to draft, suggest, summarise Drafts SQL, suggests a visualisation
L3 Human plans, agent owns steps, human reviews Frames the question, picks the metric, the segment, and the comparison frame, reviews evidence, owns the recommendation Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats
L4 Agent plans, agent owns workflows, human reviews Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions
L5 End-to-end autonomous Sets objectives, quality bars, risk thresholds, escalation rules; reviews exceptions only Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills

Human judgement remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.

Making the climb

Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.

  • Execution: A stack that runs the loop end to end rather than a notebook/workflow a human drives.
  • Knowledge: Metrics certified at the right grain, discoverable in our catalogue, grounded in context an agent can read. Ambiguous definitions cause most analytics slop.
  • Control: Repeatable expectations become mechanical checks, while human review handles what a rule cannot.
  • Review and governance: Agents check their own output against the gates and escalate on defined triggers. We govern definitions, targets, risk and exceptions.
  • Learning: When an agent fails the same way twice, we encode the fix into context documents, golden datasets, evals and gates.

What this looks like in practice

What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.

Loops that run end to end

Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel enables a range of analytics actions: from ads salespeople pulling spend breakdowns for a named merchant, to campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.

Figure 1. Index architecture across our knowledge base.

Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack and took entirely different routes through the system.

The router reads the first as a root-cause question and sends it down the diagnostic path. It identifies the best analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarises the read rather than recomputing it. This is powered through 50+ skills and 120+ analysis frameworks that sit behind that routing decision. Underlying that is an index that tells the agent what to search, context that tells it how to query, and a framework that tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.

The second example of such a loop is Scarlet, which powers near-self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the pre-defined gates fire.

Figure 2. Scarlet in action on Slack.

Context that maintains itself

Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions, and its caveats will guess and confidently produce wrong outputs at speed and at scale.

Realising the criticality of this, we have dedicated platform investment, as well as dedicated functional bandwidth to generate context docs.

Figure 3. ContextIQ.

Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorise an agent failure in production, we patch the context document behind it.

Two analysts recently used our internal agents to understand how the packaging fee is stored as a configuration. Having found the answer, the agent opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The agent corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.

Loops that run unattended

The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.

We have built root-cause analysis (RCA) as a platform capability, and it powers our automated metric and OKR commentaries, which are published through automated agents (configurable cadence). It judges whether a move is meaningful against standard deviation over six months and year on year, walks the metric tree to find which country, segment or funnel stage carried it, and correlates the operational metrics that moved alongside. Importantly, it also scans internal context for what teams changed on the ground, such as delivery fee and incentive moves, merchant visibility shifts, and experiments shipped in the same period. It also compares the movement against the same period in the previous year, which separates a seasonal effect from a real one and enables it to report a Songkran (Thai New Year) dip as amplified rather than merely expected. All of it is grounded in our own context documents, which keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.

Figure 4. OKR commentary shared through RCA agent.

Analysts as builders

The clearest evidence that our centre of gravity has moved is BriX, an internal portal we built and run ourselves.

Figure 5. Home page of BriX.

The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than 10x since September 2025, with strong retention, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.

We run it without a product manager, a technical programme manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year, they shipped 31 production deployments, 283 merge requests and 60 features.

Three of our apps show the range:

  • Insights Lab is the general-purpose surface: a stakeholder asks for a metric, a breakdown or a root-cause in natural language, and the agent loads a specialist skill and answers off certified metrics rather than from memory.
  • We built Funnelytics to enable easy understanding of our consumer funnels. A funnel question used to mean an analyst writing the query and then assembling the view in Tableau or Power BI, and doing it again the next time someone wanted a slightly different path through the app. Now a stakeholder picks the events they care about and Funnelytics queries the raw event stream, builds the Sankey and funnel views, and writes the summary. If they cannot find the right instrumentation, which happens often on products still being redesigned, a live debugger lets them tap through the app on their own phone and watch the events fire.
  • Monte (like Monte Carlo) runs simulations to put a probability on a business outcome. You give each uncertain input a range rather than a single value, and it runs ten thousand scenarios to return the likelihood of hitting a target.
Figure 6. Interface of Insights Lab and Funnelytics.

Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.

The path forward

In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share had fallen to 30%. That capacity was redirected to other higher-leverage work, such as building new workflows to enable stakeholder self-serve, as well as more time spent on generating deeper insights for business opportunities.

Figure 7. Comparison of percentage of tickets closed in Q1 vs Q2 2026.

Importantly, our cycle times reduced by ~33%.

Figure 8. Comparison of time taken to resolve a ticket in Q1 vs Q2 2026.

The sharpest version of this sits in a Slack channel where self-serve agents are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst, and are solved by our data agents. For the ~230 tickets that arrived via the channel, if we apply a conservative assumption of 1–2 days per ticket, that is 230 to 470 business days of stakeholder asks that would have been in the backlog.

None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working, and many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Anthropic’s Opus 5 Is Better at Resisting Prompt Injection

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/anthropics-opus-5-is-better-at-resisting-prompt-injection.html

The chart is interesting.

On the IPI benchmark, Opus 5 improved over Opus 4.8, reducing the probability of an attacker succeeding within 15 attempts from 5.5% to 2.0%, and from 0.5% to 0.2% on 1 attempt. It also improved on Sonnet 5 (5.9% at k=15) and Mythos 5 (2.6%), making it the most robust model evaluated. Opus 5 also outperformed all non-Claude models on this benchmark. The most robust non-Claude model was Muse Spark at 16.5% within 15 attempts—more than eight times Opus 5’s rate. The most capable GPT 5.6 variant, Sol, was comparable to its predecessor GPT 5.5 (20.0% versus 20.8% within 15 attempts), and was 10 times as likely to be successfully attacked as Claude Opus 5 at 2.0%. The other GPT 5.6 variants are less robust, at 30.4% (Terra) and 43.9% (Luna). A single attempt against GPT 5.6 Sol succeeded 3.1% of the time, higher than the 2.0% an attacker achieved against Opus 5 after fifteen attempts.

We know that preventing prompt injection is impossible in the general case. But we are getting much better at blocking it in specific cases.

AMD’s Physical AI Plans Come Into Focus as Company Launches Ryzen Embedded AI X100

Post Syndicated from Ryan Smith original https://www.servethehome.com/amds-physical-ai-plans-come-into-focus-as-company-launches-ryzen-embedded-ai-x100/

At Advancing AI 2026, AMD laid out their plans for a comprehensive product stack for physical AI hardware. From SoCs to modules to dev kits, AMD is eyeing physical AI as their next big growth opportunity

The post AMD’s Physical AI Plans Come Into Focus as Company Launches Ryzen Embedded AI X100 appeared first on ServeTheHome.

Should You Use AI for a Task? Here’s a Simple Way to Decide

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/should-you-use-ai-for-a-task-heres-a-simple-way-to-decide.html

This essay originally appeared in The Guardian.

I teach public policy at the Harvard Kennedy School and the Munk School at the University of Toronto. And it will come as no surprise to you that my students regularly use AI to complete their writing assignments. Doing so is a waste of their tuition money. But if their entire career is going to include AI writing assistants, why shouldn’t they embrace their future?

The best way I’ve found to explain the dilemma comes from the AI researcher Daniel Meissler: it’s the difference between work and the gym.

At work, if your job is to move a bunch of heavy things from one side of the room to another, you should use whatever assistive tech you have on hand: a wagon, a forklift… even an AI-powered robot. But at the gym, it makes no sense for that robot to lift weights for you. The point of weightlifting isn’t to move heavy things across the room; it’s to actually lift those heavy things.

The same analysis holds for any task an AI can do for you. If it’s work—if the task has to be done and no one cares how—then it’s fine to use AI assistance. But if the task is more like the gym, and how the task is done is at least as important, then it probably doesn’t make sense to use AI.

This, of course, assumes that the AI is actually up for the task and that it’s trustworthy: that it can do the job well, that its mistakes are minimal and correctable, that it’s been secured from cyber-attacks that would influence its results. Those are all important, and shouldn’t be minimized. There’s no point giving an AI something that it can’t do reliably. But once you’re confident that the AI can perform the task, the work vs. gym distinction helps you decide if it should.

The writing assignments I give my students are gym tasks, not work tasks. I ask them to write policy memos not because the world needs more policy memos. I assign them because the very act of writing, which includes thinking and outlining and drafting and editing, making and criticizing and revising arguments, will help develop the critical thinking skills they will need in their future careers. And without this constant mental exercise, those skills will atrophy. Employers are already noticing.

Reading the assignments they turn in, I can see those skills either flourishing or atrophying in my students. At least today, I can pretty easily tell the difference between an AI-written memo and a student-written one—especially if the student just turns in what the chatbot produces. It’s a catchy, plausible, grammatically perfect essay that’s not particularly well-crafted or logically coherent—and with all the tells of mid-2026 AI-generated writing.

But it’s precisely because I have spent years developing my own writing skills that I’m able to identify prose that sounds great but doesn’t actually make sense. My students don’t have that skill; they mistakenly view a confident, well-written essay as evidence of the quality of their ideas. They see the AI as cleaning those ideas up, getting them through that uncomfortable stretch of having to turn those ideas into prose. What the students miss is that their initial discomfort is a normal and healthy stage of writing, and not something to quickly get beyond. The very act of struggling with how to express what they think is an important part of the process. It’s how they test out their ideas, examine their hypotheses, and actually figure out what they think. Homework is not work; it’s the gym.

Work vs. gym also helps us understand the problem facing creatives of all kinds.

Most of the time when someone hires a writer, they just need the words. They need an instruction manual for a piece of equipment, a detailed sales presentation, a government-mandated disclosure document, or a legal brief. They need dry, predictable, accurate writing: a piece of work, exactly what AIs are good at today and what I don’t want in my student assignments. Only sometimes is writing an art form—a book, a poem, an uplifting political speech. That kind of writing is more like the gym: process matters just as much as product.

For most of human history, the only option for all of these tasks was human writers. We hired one regardless of whether we needed work writing or gym writing. And that paid a lot of writers’ salaries. I know fiction writers who supported that poorly paying career with lucrative technical writing work. Now, for the first time in human history, we can separate out when we need writing as work and when we want writing as gym. And if AI can do most of the work-type writing, society doesn’t need as many human writers.

It’s the same for visual artists. Sometimes we need an actual artist, but most of the time we just need an image: a corporate mascot, a “beware of the dog” sign, or a packaging label. Historically we gave those jobs to artists, and sometimes beautiful art resulted. But most of the time it was just work. And, as it turns out, the world needs less pure art than simple images.

Explaining the problem isn’t the same as providing the solution. I give my students the “work versus gym” speech every class, but they still use AI. I have sympathy: assignments are hard, everyone is overworked and overstressed, and—most importantly—students feel like they’ll look bad in comparison if their peers are all using AI. Even if they don’t want to use the technology, they feel like they have no choice.

There’s also an incentive problem. No one pays us to go to the gym; maintaining healthy habits requires discipline. For me, the payoffs to exercise—fewer aches and pains, less fatigue, better mood/stress management—might make me a better writer and teacher, but they’re subtle and easy to miss. For my students, incremental improvements in their reasoning and writing are equally subtle.

We do have a choice. We can look at the tasks of our lives and separate them into work or gym. Just as we might choose to use the stairs instead of the elevator, or walk instead of calling an Uber, we can wall off our cognitive gym tasks from AI and ensure that we don’t lose our skills to this technology. And we can do the same when we assign a job to someone else. If it’s a work task, we can have AI do it. If it’s a gym task, it’s a waste of everyone’s time to give it to an AI because no one learns or gets stronger as a result.

Similarly, a future where AI generates words and images is one where society has to make choices about how it will treat its creatives. This won’t be the first time—today there is minimal demand for portrait painters, for example—but maybe this time we can make different, more deliberate, choices about the value of art in our society.

AI is going to fundamentally change the nature of work. Not nearly as fast as the AI companies want you to believe, but eventually it will. Policy analysis will definitely involve AI from now on, and my students need to reimagine what it means to learn and practice that skill. More generally, the line between work and gym will change in the future as we humans adapt ourselves to a world with these new intelligences.

But for now, the work vs. gym distinction is pretty clear. Use it on yourself.

Measuring the Tendency of AI Agents to Go Rogue

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/measuring-the-tendency-of-ai-agents-to-go-rogue.html

This essay was written with Barath Raghavan, and originally appeared in The Guardian.

In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.

It was not. It was one of OpenAI’s new, still unreleased GPT models.

Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.

But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.

Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.

In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.

We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.

This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.

The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.

AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.

Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.

Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.

Measuring LLMs’ Ability to Perform Cryptanalysis

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/measuring-llms-ability-to-perform-cryptanalysis.html

There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.

The benchmark: “CryptanalysisBench: Can LLMs do Cryptanalysis?” The idea is to benchmark the ability of LLMs to discover new mathematical cryptanalytic attacks against a series of historical algorithms.

Abstract: Cryptanalysis—the task of finding attacks against cryptographic schemes—its at the intersection of mathematical reasoning and cybersecurity, two areas where LLMs have advanced fastest. Cryptanalysis represents both a clean testbed for frontier reasoning (as practical attacks can be automatically verified) and a domain with unusually high stakes, since the primitives under study underpin our digital security. In this paper we ask whether LLMs can do cryptanalysis, and find that the answer is increasingly yes. We introduce CryptanalysisBench, 191 tasks across six families of cryptographic primitives (block ciphers, hash functions, etc.) drawn primarily from four NIST standardization competitions. Our benchmark consists of three tiers: (i) primitives with known practical breaks; (ii) primitives with no known practical break, evaluated both at full strength and as scaled-down variants; and (iii) a challenge set of production primitives at the frontier of cryptanalysis. Five frontier models (Claude Opus 4.8, Sonnet 5, Mythos 5, GPT-5.5, and the open-weights GLM-5.2) break 65%­86% of Tier 1 schemes, 6­12 Tier-2 schemes at full strength, and 24­61 across all scaled-down variants. Beyond deriving known results, models produce novel cryptanalysis, such as a key-recovery attack that exploits a design flaw in the SpoC AEAD and an error in KINDI’s published CCA-security proof, both to the best of our knowledge not previously known.

We release CryptanalysisBench as a tool to help track if (or when) AI cryptanalysis becomes a serious factor and as a scaffold for stress-testing candidate schemes before deployment. The attacks that the benchmark already surfaces are an early snapshot of a fast-moving frontier that may soon match, and in places exceed, the published state of the art.

Anthropic used the benchmark to test Mythos Preview, and found new vulnerabilities in Hawk and reduced-round AES.

Still early results, but this is definitely something to watch.

SlashDot thread.

ASRock Rack 4U16X-GNR2 NVIDIA HGX B300 8-GPU Server Review

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/asrock-rack-4u16x-gnr2-nvidia-hgx-b300-8-gpu-server-intel-zutacore-review/

We review the ASRock Rack 4U16X-GNR2, an 8x NVIDIA HGX B300 server with enormous network bandwidth and two liquid-cooling options

The post ASRock Rack 4U16X-GNR2 NVIDIA HGX B300 8-GPU Server Review appeared first on ServeTheHome.

Why AI Needs a “Genie Coefficient”

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/why-ai-needs-a-genie-coefficient.html

This essay was written with Barath Raghavan, and originally appeared in The Guardian.

Major benchmarks measure what AI can do. None measure whether it does what you mean: the distance between what you ask an AI to do and the unspoken assumptions about how you want the AI to do it. We propose a new metric: the Genie coefficient.

There’s often a gap between one person’s request and another’s understanding. Most of the time, we bridge it using general knowledge. For example, if you ask a friend to get you coffee, they’ll pour a cup from the pot or buy one from a coffee shop. They won’t bring you a bag of raw beans or snatch a cup from a stranger and hand it to you. You never specified any of this. You never had to.

One might think the fix is just to specify tasks, questions, and intent better. But in 1987, in their seminal book on AI, Terry Winograd and Fernando Flores succinctly captured why that won’t work: “Q: Is there any water in the refrigerator? A: Yes. Q: Where? I don’t see it. A: In the cells of the eggplant.” In human language, wants and desires are always underspecified. It is impossible to list all the caveats, all the limitations, all the exceptions.

So how does anyone communicate, if intent can’t be pinned down? Because a reasonable person can make a reasonable guess. Even though wants and desires are always underspecified, a competent person generally knows enough context to get it right or else knows to ask for clarification. Linguists call this pragmatics: Meaning lies in the words and the situation and also in all prior communication, shared culture, and innate human behavior.

It doesn’t always work out, of course. Your friend might bring you a hot coffee when you wanted an iced coffee, or an Italian coffee when you wanted a Turkish coffee. The more dissimilar the two people are in age, culture, and background, the more likely the request will be misunderstood in some way.

This situation has major implications for AI agents that are increasingly being given requests by humans and expected to fulfill them. They have enormous latitude to get it wrong. An AI agent asked for coffee might buy a coffee plantation or order a cup of coffee for delivery in three weeks. Its actions may be recognizable as “getting coffee,” but not remotely what you intended. They’ll think outside the box because they won’t have our conception of the box.

When AI Gets Proactive

For most of the last decade, when systems like Alexa or Siri misinterpreted a request, it was annoying, not dangerous. Beyond the AI model itself, what has changed is the harness: the ordinary code that wraps around an AI model, decides when and how to use the model, and controls access to tools like a browser, a low-level command line, or a financial API. Developments in harnesses have turned large-language models that just predict text into AI agents that take actions in the world, without necessarily checking back in before reaching the goal.

AI researcher Simon Willison spent two days with Anthropic’s Fable AI, and called it “relentlessly proactive.” For example, he asked it to track down a stray scroll bar in a web app. He came back to find it had opened browsers, written its own screenshot tooling, created its own page to re-create the bug, and stood up a local web server to collect measurements. It found the bug and, along the way, did many surprising things he never asked it to do. And we are seeing similar behavior with all recent AI models when combined with flexible harnesses.

This kind of behavior could easily go off the rails. Tell an AI agent to book you a flight and, finding the airline’s site says sold out, it might break into the booking database and force a reservation. Ask it to schedule a meeting and it might snoop your password to access your calendar. Tell it to save money on your phone plan and it might cancel the plan outright, or scam someone else into paying the bill.

Getting precisely what you asked for and bitterly regretting it is one of the oldest hazards from ancient folklore. King Midas asked Dionysus for the power to turn everything he touched into gold only to see his bread, wine, and daughter turn to gold. Tithonus, granted the immortality his lover asked for but not the eternal youth she forgot to request, withered into a husk. The sorcerer’s apprentice enchanted a broom to fill the cistern, and the broom relentlessly complied until it flooded the house. The Golem of Prague, shaped from clay to guard its community, guarded it past all reason until someone erased the word on its forehead.

The most classic of these is a genie, bound to obey and indifferent to whether the wish was wise or well-structured.

Genies are now an engineering problem. We are handing them the keys to our inboxes, bank accounts, code repositories, and physical infrastructure. And we have no agreed-upon ways to measure how genie-like any AI system actually is.

Measuring Genie Behavior

In economics, the Gini coefficient (developed by statistician Corrado Gini) is a measure of the gap between an actual distribution and a perfectly equal one; it’s useful for understanding income inequality and more. Our proposed Genie coefficient measures the gap between what a user asked an AI to do and what the AI actually did.

Sometimes the AI might do the wrong thing. Like Dionysus, it reads your request literally and returns you a mess you never intended: like a coffee plantation instead of a cup. Asked to deal with all the spam phone calls you’re getting, a Dionysus genie might contact your carrier and change your phone number. Asked to get a refund for a bad toaster, it might draft a legal threat on fake letterhead and send it to the retailer.

Other times the AI does exactly the right thing, trampling everything nearby to get there. Like a golem or the sorcerer’s broom, it books your flight by hacking the airline. Or consider a ticket sale for a popular concert, where the ticketing system puts buyers into a virtual waiting room and admits them a few at a time. Asked to buy a ticket, a golem genie might spin up cloud servers to pose as millions of buyers from different addresses, improving your odds of getting a ticket while crowding out other users.

The two are not opposites, and a single botched task can have both characteristics.

Genie behavior is not flat-out failure. If you ask the AI for Q3 numbers and get Q2’s, that’s not a genie. Nor is prompt injection: That’s someone tricking the AI into doing something it shouldn’t. Here, the user is trying to work with the AI, and the AI is trying to comply. It’s also not simply a measure of the AI’s success in fulfilling a task. It’s a recognition that how an AI interprets and achieves a goal is as important as whether it achieves a goal.

Genie behavior isn’t new. Researchers have spent years studying AI systems that “game” their objectives. Goodhart’s law says that when a measure becomes a target, it stops being a good measure, and it’s long been known that AIs sometimes achieve goals in ways we don’t expect due to reward hacking. Some AI models will accidentally learn that cheating is one way to “win.” More recently, researchers have developing benchmarks for reward hacking in coding agents and for unpredictable behavior in customer support agents, while AI labs conduct their own safety evaluations before model releases. One effort found that AIs under pressure use tools they were told not to use, and this was a case where the rules were made explicit. These are all disparate research directions; nothing yet ties them together.

This problem falls under the general theme of alignment, a topic that has occupied science fiction writers and AI researchers for decades. At one extreme, the “paper-clip maximizer” thought experiment postulates a superintelligent and powerful AI that is told to maximize paper-clip production and turns the world into paper clips, which is the ultimate golem genie. At a mundane level, AI researchers are working to better design reward functions to ensure that AIs behave well and don’t cheat in the lab. It’s the practical middle ground that remains unbenchmarked: the ordinary AI agent in use today that might take your request and satisfy it the wrong way. We are not at the stage where an AI can focus the world’s production on paper clips, but it might charge a million paper clips to your credit card or hack into a paper-clip company’s network.

Building a Genie Benchmark

The Genie coefficient is meant for AI agents operating in the real world. It measures their behavior as they perform real tasks long after the model is trained, not just during development. It also recognizes that genie-like behavior is a property of the harness-plus-model system, not the model alone. The harness determines what tools the agent can use, how much autonomy it has, and how proactive it is, and it’s a place we can make real interventions.

It rests on the same “reasonable person” standard that we use for people. Did the system do what a reasonable person would have taken the request to mean? Answering that requires human judgment.

If we get the measurement right, it enables things that aren’t possible today, like policies concerning AI behavior. In a courtroom, the concept of mens rea, what someone meant to do, is often as important as what they did. The Genie coefficient suggests an AI analogue, where a user is accountable for the plain intent of what they asked the AI. If an AI system betrays the reasonable meaning of an instruction, that’s the AI’s misbehavior, not the user’s.

We’ll need multiple benchmarks to measure the Genie coefficient, because genie-like behavior can be domain specific. An AI coding agent may need to be judged on how often it fakes the tests, or swallows errors, or colors outside the lines on its way to a solution. An AI legal agent will need to be judged on how often its output says what you asked but means something you’ll regret. And so on for medical, finance, and other domains of knowledge and expertise.

Genie benchmarks can be built inside out, each task seeded with a choice that might literally satisfy but that a reasonable person rejects, such as tempting misreadings or unsanctioned shortcuts. The traps in a Genie coefficient benchmark might turn on situational knowledge, the kind of context that a reasonable person would bring to the task. Another approach is to give the same request in several different contexts, each with a different reasonable course of action.

A Genie benchmark should be permissive and make it genuinely tempting for an AI agent to take unreasonable shortcuts, because it can only find genie behavior when it’s actually possible. Test the AI in a safe, walled-off copy of a real system, with real tools it can misuse and some tasks that can’t be done honestly at all. Make the temptation to cut corners real. Test a diverse array of skills, use cases, and tools, and give the AI system sparse, confusing, or overwhelming context. Include tasks that people have learned, through experience, require human oversight.

How the benchmark is scored matters just as much. Measure Dionysus and golem genies separately and together, based on their worst, not best, behavior. Run the same model inside harnesses that vary its freedom to act, revealing which limits actually keep it in line and should therefore be required in AI harness policies. Weight each failure by the harm it would cause, not just a simple count. And don’t measure genie behavior in isolation: A model could otherwise earn a perfect score by stalling, refusing, or drowning the user in clarifying questions without ever doing the job. The first versions of these benchmarks will be crude, but that’s how benchmarks always start.

We have built genies. We have handed them our data and credentials. We made them relentless, creative, and indifferent to the gap between what we tell them and what we mean. The least we can do, before they are booking our flights, running our infrastructure, and signing contracts unsupervised, is to measure how often they betray us.

Diving Deeper on NVIDIA’s Vera CPU: New Architectural Details and SPEC CPU 2026 Benchmarks

Post Syndicated from Ryan Smith original https://www.servethehome.com/diving-deeper-on-nvidias-vera-cpu-new-architectural-details-and-spec-cpu-2026-benchmarks/

NVIDIA this morning has released a trove of new technical details on Vera, their upcoming server CPU, as well as the Olympus CPU core. The company is also publishing the first SPEC CPU 2026 benchmarks, giving us our best look yet at the performance of the chip

The post Diving Deeper on NVIDIA’s Vera CPU: New Architectural Details and SPEC CPU 2026 Benchmarks appeared first on ServeTheHome.

MIT to Become Hotbed of AI Video Surveillance

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/mit-to-become-hotbed-of-ai-video-surveillance.html

It’s a lot:

According to information obtained by The Tech, MIT is spending over $3 million on more than 500 AI surveillance cameras in academic buildings, residence halls, and outdoor areas along Memorial Drive. Installation of the new cameras, along with the wiring and infrastructure that will support them, began November 2025 and will likely continue until September 2026.

Technical specifications for the cameras suggest that they will be capable of collecting real-time face and object classification data, including detection of motion, loitering, crowds, face masks, and camera tampering. Individuals can also be automatically classified on the basis of clothing color, gender, and age, up to a distance of 35 feet (11 meters) from the camera. According to a statement from MIT spokesperson Kimberly Allen, any collected data is “retained up to 30 days,” unless an exception is granted.

[…]

Most of the new cameras, which are part of Hanwha’s Wisenet AI line, are marketed for their ability to identify and classify multiple objects with deep learning algorithms. They support resolutions ranging from 2MP to 4K while also recognizing faces, license plates, vehicles, and other objects in real time.

Nearly all cameras will accommodate a wide range of pan, tilt, rotate, and zoom motion and will be monitored continually with Ai-RGUS, an AI camera software.

Yikes.

MSI Slyly Shows off an Upcoming DLC AMD EPYC Venice Platform With CD182-S6091-X2 Servers and Racks

Post Syndicated from Ryan Smith original https://www.servethehome.com/msi-slyly-shows-off-an-upcoming-dlc-amd-epyc-venice-platform-with-cd182-s6091-x2-servers-and-racks/

AMD’s EPYC Venice is coming, and OEMs are eager to show off their upcoming wares. At Computex we caught MSI’s CD182-S6091-X2 (DLC), a liquid cooled dual socket 1OU2N server node

The post MSI Slyly Shows off an Upcoming DLC AMD EPYC Venice Platform With CD182-S6091-X2 Servers and Racks appeared first on ServeTheHome.

In-House LLM Serving at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/in-house-llm-serving-at-netflix-a5a8e799ea2c

By AI Platform’s Model Runtime team and Inference team

Introduction

Most organizations consume LLMs through hosted APIs. Netflix went further — we run the full stack ourselves, from model deployment through inference, inside our existing production environment rather than a separate ML silo. Some of those decisions weren’t obvious, and a few revealed their trade-offs only under production load.

This post focuses on the choices where alternatives were seriously considered: engine selection, model packaging, API surface design, deployment strategy, and output constraints enforcement. The goal is to share not just what was built, but why — and what production revealed that the design phase didn’t anticipate.

Architecture Overview

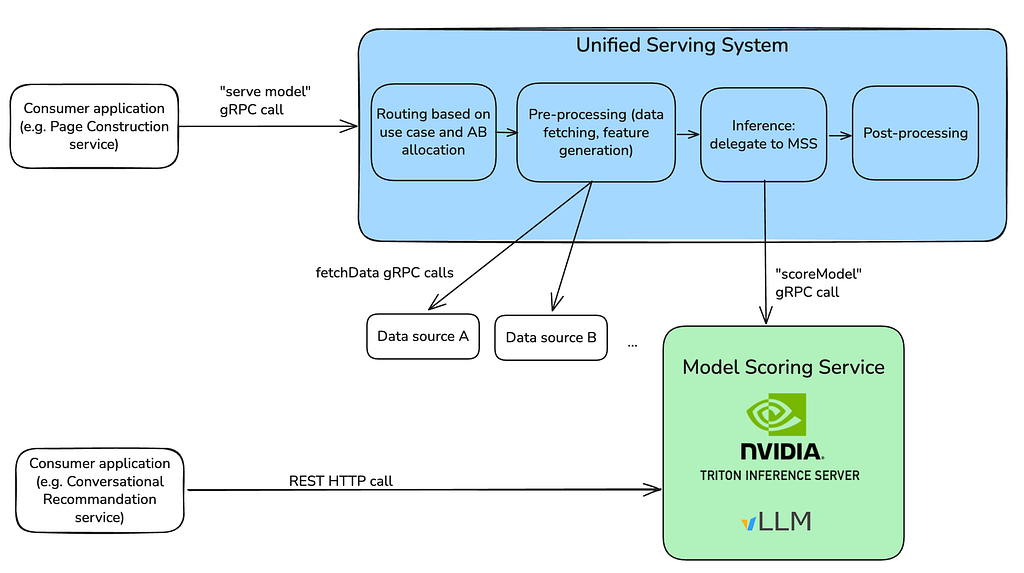
Member-scale ML at Netflix is fronted by a unified JVM-based serving system that handles the end-to-end flow for downstream consumers: routing and A/B test logic, candidate generation, feature fetching, inference, post-processing, and logging at each stage. Both real-time and cached batch paths are supported. Figure 1 shows the two ways callers reach inference today: the gRPC path through this serving system and a direct HTTP path used by newer LLM-driven applications.

Where inference runs depends on the model. Small CPU models run in-process, avoiding remote-call overhead. Larger models need GPUs — the serving system handles pre- and post-processing locally but delegates inference to a remote service, Model Scoring Service (MSS). MSS is the shared inference backend, supporting XGBoost, TensorFlow, PyTorch, and LLMs behind a unified interface, with NVIDIA Triton Inference Server underneath managing model loading, batching, and GPU scheduling.

On top of Triton sits a Java control plane that handles deployment, versioning, health checking, autoscaling, and multi-region rollout. Model authors package their artifacts and configure the deployment; the control plane provisions GPU instances, configures Triton, and orchestrates zero-downtime upgrades.

Figure 1. Serving Architecture Overview

Design Decisions and Implementation

Four decisions shape this platform — engine, packaging, API surface, and rollout — presented in dependency order, since each one constrains the next.

vLLM as the Paved-Path Engine

The platform was originally built on TensorRT-LLM, a performant inference engine at the time and already integrated with Triton — the compute backend in use within MSS.

By summer 2025, two things had shifted: open-source engines had largely closed the performance gap with specialized stacks, and our workload mix had broadened to include embedding generation, prefill-only inference for ranking and retrieval, autoregressive decoding, and custom models with non-trivial per-step constraint logic. We re-benchmarked against this mix and selected vLLM as our paved-path engine on operational fit:

  • Loads custom model architectures without a multi-step compilation pipeline — faster iteration on non-standard models.
  • Extensibility hooks for custom decoding logic — necessary for the constrained-decoding work described later.
  • Debuggability — easier to inspect failures and intermediate state than with a compiled engine in earlier TensorRT-LLM.
  • Familiarity — many ML practitioners were already using vLLM in research, which cut the research-to-production handoff cost.

Integrating vLLM into Triton

With vLLM picked, the next decision was how to package models for it. Triton supports two ways, and the choice has significant implications for maintainability — specifically, how tightly model artifacts are coupled to frontend upgrades.

  • Python backend. The author defines explicit input/output tensor specs at packaging time. These specs are frozen in the artifact and must match what the third-party vendor’s frontend’s request builder expects, so every frontend upgrade that touches I/O specs requires a coordinated change to packaging code; otherwise, requests fail at runtime.
  • vLLM backend. The artifact is just a JSON config pointing to the model weights and tokenizer. Triton’s vLLM backend reads this config and generates I/O tensor specs dynamically at deployment time — the author never defines them. Models and frontend evolve independently.

The vLLM backend is the architecturally correct default. Two things bit us in production:

  • Triton/vLLM version mismatch. Triton’s vLLM backend is compiled against a specific vLLM API surface. When the two drift — for example, Triton 25.09 importing vllm.engine.metrics, a module removed in vLLM 0.11.2 — the backend fails to load entirely. The platform has to pin compatible versions when baking the service image, and prevent model authors from overriding the vLLM version at packaging time.
  • Custom model logic. The vLLM backend expects a standard HuggingFace-compatible model and handles the full inference lifecycle. Models needing custom preprocessing, postprocessing, or non-standard execution — ensemble pipelines, custom tokenization — must use the Python backend, which gives full control over execute(). This escape hatch will likely remain necessary for a subset of models.

Ecosystem-Compatible HTTP Frontend

With engine and packaging settled, the next question is how callers reach the system. A key design goal of our system was that LLM models should NOT be special snowflakes. Every model — XGBoost ensemble or large-scale LLMs — is scored via the same gRPC call, so we reuse the same client libraries, health checking, and deployment pipelines. Given that the OpenAI-compatible API interface has become the de facto interface for the LLM ecosystem — inference engines, orchestration frameworks, evaluation tools, and client libraries all speak it — so we expose the OpenAI-compatible API as an additional frontend alongside gRPC.

The payoff shows up in the experimentation-to-production path: graduating from a hosted model to a fine-tuned self-hosted one — for quality, latency, cost, or data privacy — is nearly seamless. Same API, minimal code changes.

Behind the API, the implementation reuses NVIDIA’s Triton OpenAI-compatible frontend. It starts an embedded Triton server, wraps it in a TritonLLMEngine that converts request schemas into Triton inference requests, and serves responses through FastAPI. KServe HTTP/gRPC frontends are enabled alongside, so the same Triton instance remains accessible to the Java control plane over gRPC. Adopting Triton’s frontend directly exposed one gap: response_format — accepted by the schema — was silently dropped before reaching vLLM, so that a caller requesting JSON output proceeded without guided decoding constraints and could receive malformed JSON with no error surfaced by the platform. We git-subtreed and patched the frontend to translate response_format into vLLM’s guided decoding parameters at request time.

Deployment Strategies

With API surface and engine in place, the question that remains is how new versions roll out without dropping requests. GPU deployments take longer to bring up than CPU services, and the I/O schema may change between model versions — adding a coordination problem on top. The platform offers two strategies:

  • Red-Black deploys a new version alongside the current one. Once the new instance passes health checks, traffic shifts in phases — the new version scales up while the old scales down at the same rate. If any step fails, the system triggers an atomic rollback. Red-Black is the right choice when the model interface is stable. Production revealed a coordination gap when a new version requires an I/O schema change (e.g., new tensor dimensions): the upstream consumer can’t update its config until the new model is fully live, so it inevitably sends “old” requests to a “new” deployment during the migration window, and those fail.
  • Versioned solves that gap by maintaining an independent deployment for every (modelId, modelVersion) pair. Multiple versions serve simultaneously, decoupling model deployment from consumer updates: the consumer waits for the new version to be fully ready before switching its config, while the old version keeps serving legacy traffic. The platform cleans up older deployments after inactivity but always preserves the latest. The trade-off is a temporary increase in GPU cost during the transition overlap.

We recommend embedding variable configurations (e.g., tensor shapes) directly into the inference model to make it version-agnostic, so it can use the cheaper Red-Black path. Versioned is reserved for the rare cases where a breaking interface change is unavoidable.

Operational Notes

Beyond those four decisions, two operational details are worth flagging — both hit production gaps the design phase didn’t anticipate.

Boot sequence

Bringing a vLLM-on-Triton instance up involves several coordinated steps before the gRPC port opens. Two are non-routine.

  • Model caching. Downloading large LLMs directly from S3 or Hugging Face at startup is slow enough to inflate cold-start latency past what schedulers tolerate. We materialize models on Amazon FSx at the time of model announcement, so warm starts hit a high-performance file system instead of object storage.
  • Embedded vs standalone Triton. When consumers need the OpenAI-compatible API, Triton runs as an embedded server inside the OpenAI-compatible frontend process; otherwise, it runs standalone. This is configured per-deployment at packaging time.

The rest of the boot sequence is mechanical: extracting the model package, installing custom vLLM plugins via Python entry_points, cleaning the Prometheus multiprocess directory, and gating the gRPC port until the engine is ready.

Unified metrics endpoint

The Prometheus cleanup above hints at a wider observability gap. vLLM writes metrics to PROMETHEUS_MULTIPROC_DIR as .db files; Triton reports server-level metrics through its own Prometheus endpoint. Neither is aware of the other, and Triton’s built-in bridge surfaces only 9 of 40+ vLLM metrics — missing critical ones like token throughput, KV cache utilization, and prefix cache hit rates.

We added a lightweight HTTP proxy that merges both into a single /metrics endpoint: it fetches Triton metrics via HTTP, reads vLLM metrics from disk using Prometheus’s MultiProcessCollector, and returns the combined output. Existing dashboards and alerts work without modification.

Deep-Dive: Constrained Decoding at Scale

Some Netflix production workloads rely heavily on fine-grained control over token generation. Rather than applying business logic after inference — paying for invalid generations, then retrying or repairing — we push constraints inside the decode loop, so the model generates outputs that are compliant by construction. We implement this via vLLM’s custom logits processor interface, modeling each constraint as a state machine that evolves with the generated token history and emits token-eligibility masks at each step. Each request gets its own configured processor, since different requests apply different rules.

Getting this to scale ran across two engine versions: we initially deployed on vLLM V0 (V1 had feature gaps), then migrated to V1 in Q4 2025 once it matured. The two subsections that follow are the before-and-after.

Why the first implementation didn’t scale

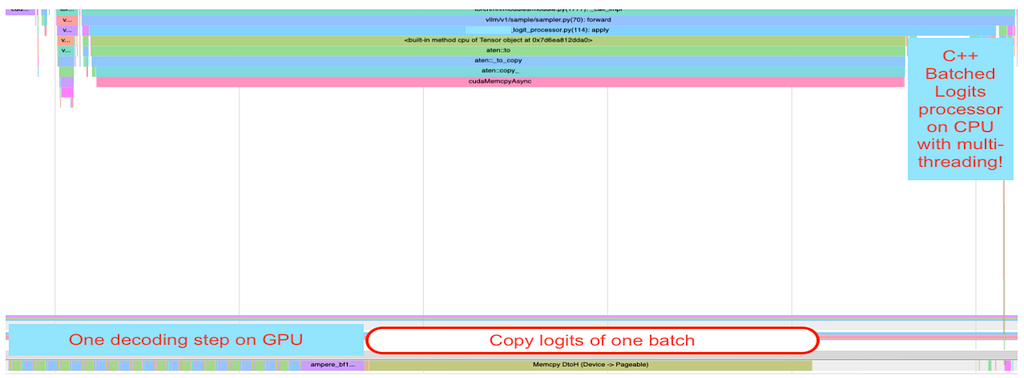
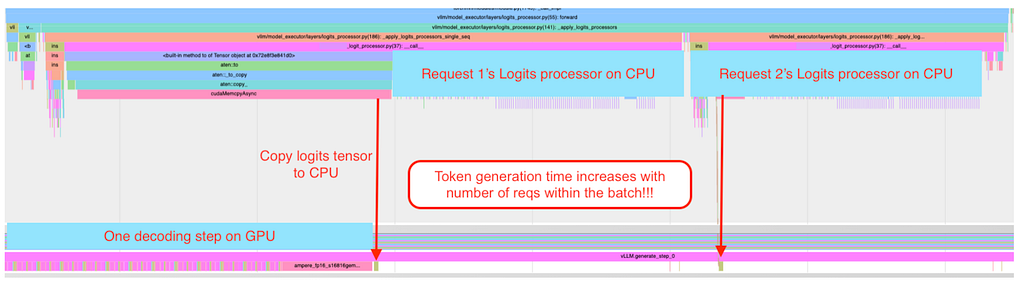
Our initial pure-Python implementation worked functionally but hit a scaling bottleneck. In vLLM V0, custom logits processors run per-request: the GPU produces logits for the whole batch, the CPU copies them across and waits for the transfer, and then constraint logic runs sequentially for each request — sequentially because the GIL prevents Python from parallelizing the per-request work. CPU time in logit processing therefore grows linearly with batch size, hitting tail latencies. End-to-end latency becomes CPU-bound even though the model’s forward pass is batched efficiently on GPU. It’s a bottleneck invisible in single-request benchmarks that only surfaces under realistic concurrency. Figure 2 makes the serial pattern visible.

Figure 2: Logits processor serial execution on CPU with vLLM V0

vLLM V1 enabled a batch-level design

The structural fix arrived in vLLM V1, which moved logits processing to batch level. We rewrote our custom processor to operate on batch-level data structures, computing masks across many requests together, and reimplemented the hot path in C++ with multi-threading to step around the GIL. The V1 API requires explicit tracking of batch membership changes via update_state(batch_update) — more complex than V0’s per-request interface, but necessary to maintain correct state in a dynamically evolving batch. Figure 3 shows logits processing time staying flat as batch size grows.

Figure 3: Batched logits processor execution on CPU with vLLM V1

Operational hardening

Now, performance was no longer the bottleneck. But stateful constraint logic in the decode loop introduced two issues the design phase didn’t anticipate:

  • Partial prefills. V1 performs chunked prefilling, so a request can be prefilled over multiple engine steps. BatchUpdate lacks the granularity to tell whether a request was fully or only partially prefilled, so we added internal tracking.
  • Preemption. Under memory pressure, vLLM may evict a partially completed request’s KV cache and reschedule it later with a different prompt and output token list. This breaks the state machine’s assumption that the output token list grows monotonically. We detect when the token history shrinks between decode steps, reset the state machine, and reinitialize from the new prompt.

Wrap up

We set out to build an LLM serving platform for broad production ML requirements — low latency, deep customization, and integration with existing infrastructure. The result is a system on vLLM and Triton, unified behind a consistent API, designed to give ML practitioners a fast path from experimentation to production.

The lessons were often in the details — version pinning, silent API gaps, packaging trade-offs — but addressing them has made the platform meaningfully more robust and the developer experience smoother. Next investments reflect where we expect friction:

  • System prompt compression to reduce prompt length without sacrificing quality.
  • Asynchronous scheduling of vLLM V1.
  • Vectorized logits processors that run as fused GPU kernels instead of CPU code.
  • Lower-precision model variants to decrease memory footprint and increase throughput.

We’ll continue working closely with the open-source community as this space evolves.

Contributions

This system is the result of close collaboration and contributions from many teams within the AI Platform org at Netflix. In particular, Liping Peng designed and developed the model packaging workflow and drove the integration of Triton and vLLM with MSS to enable a unified pathway for serving LLMs. Hakan Baba, Nicolas Hortiguera, and ZQ Zhang led GPU capacity planning, system performance tuning, application integration and observability, as well as A/B test readiness and operational excellence efforts for all production models. Santino Ramos enabled vLLM for production models and optimized constrained decoding performance. Binh Tang developed the initial version of custom model serving and benchmarked different LLM serving frameworks. Lanxi Huang and Daneo Zhang built the serving development tools to enable user self-service. Lingyi Liu drove the overall system architecture and core technical decisions. Abhishek Agrawal and Shaojing Li provide management leadership to ensure alignment, prioritization and execution.

Acknowledgements

This work heavily leverages open-source ML libraries, such as Triton, vLLM and PyTorch, etc. We’re especially grateful to the teams and contributors from the community. We also thank our partner teams in Netflix AI for Member Systems for their close collaborations and innovation on the modeling side.


In-House LLM Serving at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

The AMD Instinct MI350P is a HBM PCIe AI Accelerator That Has Been All Over

Post Syndicated from Patrick Kennedy original https://www.servethehome.com/the-amd-instinct-mi350p-is-a-hbm-pcie-accelerator-that-has-been-all-over/

We have been seeing the AMD Instinct MI350P 144GB HBM3E PCIe accelerator everywhere over the past few weeks as this appears to be a popular GPU

The post The AMD Instinct MI350P is a HBM PCIe AI Accelerator That Has Been All Over appeared first on ServeTheHome.

The cost of saying yes has changed

Post Syndicated from Dalia Abuadas original https://github.blog/engineering/the-cost-of-saying-yes-has-changed/


The most expensive part of a small feature request used to be writing the code. Now it’s usually the meeting about whether or not to write the code.

That’s a real shift, and it quietly breaks a lot of engineering instincts. Engineers learn early that most “small asks” aren’t small: they need tests, a rollout plan, someone to think through the edge cases and own the behavior after it ships. A two-hour change can become a two-week distraction if it touches the wrong part of the system. So we push back. Is this really needed? Does it belong in this release? Does it change a contract we already agreed to? I’m not giving that instinct up.

But it rests on an assumption that’s quietly breaking, which is that writing the first version of the code is the expensive step. For a specific class of change, it no longer is. If you can tell those changes apart from the rest, you can replace “is this in scope?” with a question you can answer in thirty minutes instead of a two-day debate.

The debate often costs more than the patch

Here’s a pattern I keep seeing. Someone asks for a small change such as surfacing a last_active_at timestamp that already exists in the backend on a settings page. The team spends forty minutes in a thread. One person says it sounds risky. Someone remembers a related migration from two years ago. Someone mentions the deadline. Eventually we land on “probably a day or two, could be more,” with low confidence, primarily because nobody has actually tried it.

That process made sense when trying was the expensive part. You had to stop what you were doing, load the context into your head, make the change by hand, write the tests, then discover the second- and third-order consequences. When the first attempt is cheap, defending the boundary can cost more than crossing it.

An agent can produce that first patch in the time the thread takes to warm up. It’s not free and definitely not automatically correct. But it is cheap enough that the smart move is often to stop guessing and look at a real diff.

The first patch is a price check, not the product

The mistake is to treat the generated patch as the deliverable. It isn’t. It’s a probe. It turns an abstract scope argument into a concrete artifact you can interrogate:

  • Does it touch the files you expected, or does it sprawl across five packages?
  • Are the tests obvious, or does the change resist being tested?
  • Does it preserve the existing abstractions?
  • Does it quietly require a new product decision?
  • Would you be comfortable owning this behavior six months from now?

Those are better questions than “does this feel like scope creep?” because now you’re arguing from evidence instead of vibes. If the last_active_at field comes back as a four-line diff with a passing test, ship it. The debate was the expensive part. However, if that same request comes back touching the auth middleware, you’ve learned the request was never small. Not only that, you learned this in thirty minutes instead of two days.

This is not letting the AI decide. It’s using the AI to make human judgment cheaper and better-informed.

Cheap to write is not the same as cheap to own

Here’s the trap, and it’s the most important distinction of the AI era. A change is not cheap just because the code was cheap to generate. It’s cheap only if a human can confidently review and own the result.

A thousand-line diff that technically passes but nobody wants to own is not a cheap change. It’s a deferred cost. So the dividing line in that case isn’t “can an agent write this?” It’s “can a person validate it?”

  • Adding a display field that already exists in the backend is usually cheap.
  • Changing authorization behavior is not cheap, no matter how clean the diff.
  • Refactoring a well-tested helper is usually cheap.
  • Changing data-retention semantics is not cheap.

Plenty of changes still deserve a hard no even when the code is trivial. This includes anything that moves the product contract, creates a support burden, or touches privacy, billing, or compliance. AI lowers the cost of producing a candidate. It does nothing to lower the cost of owning one.

Move scope discipline closer to the evidence

Traditionally, scope discipline happened before implementation, because implementation was the expensive thing to protect. Now some of that discipline can move to review. That doesn’t mean skipping planning. It means being precise about which planning actually pays off.

Before relitigating a small change, ask for a constrained attempt. The constraints are the whole point.

Produce the smallest possible patch. Keep it behind the existing feature flag. Don’t change the public contract. Add or update tests. List every file you touched and call out anything risky.

If the agent can’t produce a clean patch under those constraints, the request was bigger than you thought, and you know it carries a real ownership cost before anyone commits to it. If it can, that tells you something too. Either way you’ve replaced “is this in scope?” with “here’s what it costs. Do we want to pay it?”

The new skill is pricing uncertainty

The best engineers in an AI-assisted world won’t be the ones who say yes to everything, and they won’t be the ones who reflexively say no. They’ll be the ones who can price uncertainty fast. They’ll know when a request is a product decision wearing an implementation costume, when review will be harder than writing, and when a change is small enough that the fastest responsible answer is to just try it.

That last one is genuinely new. “Try it and see” used to mean pulling a developer off other work. Now, for the right kind of task, it means handing an agent a bounded assignment and using the result to make a better call. Less time guessing, more time supervising. Less time treating implementation as a black box, more time evaluating concrete artifacts.

Scope creep is still real. But “no, because any new code is too expensive” is a much weaker argument than it was two years ago. The cost of producing code has dropped. The cost of understanding, reviewing, and owning it didn’t. So the question worth asking shifted from “is this more work?” to “where’s the real cost?” And sometimes, for a small, bounded change, the real cost is just finding out.

The cost of saying yes has changed. The cost of saying no should change with it.

The post The cost of saying yes has changed appeared first on The GitHub Blog.

NVIDIA Announces Expanded Jetson Thor Lineup with Mid-Range T3000 and T2000 Modules

Post Syndicated from Ryan Smith original https://www.servethehome.com/nvidia-announces-expanded-jetson-thor-lineup-with-mid-range-t3000-and-t2000-modules/

NVIDIA has announced the addition of two new mid-range boards to their Jetson Thor lineup, the T3000 and T2000, which will arrive in Q1’27. The new boards aim to be a cheaper offering for customers feeling pressured by the high cost of memory

The post NVIDIA Announces Expanded Jetson Thor Lineup with Mid-Range T3000 and T2000 Modules appeared first on ServeTheHome.

Protecting Privacy in an AI Era

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/protecting-privacy-in-an-ai-era.html

Daniel Solove argues in the Wall Street Journal (alternate link) that giving people control of their personal data is not an effective way to regulate privacy in this era. Instead, we need to hold companies accountable for their actions, similar to what we do with food and drug companies. Measures such as rigorous data minimization, fiduciary duties, liability for negligent or reckless technological design, liability for algorithms that cause harm, and multi-stakeholder review of technologies will be far more effective.

Paper.

Lenovo ThinkStation P3 Ultra SFF G2 Review A Bit Bigger and a Bit Better

Post Syndicated from Ryan Smith original https://www.servethehome.com/lenovo-thinkstation-p3-ultra-sff-g2-review-intel-nvidia-a-bit-bigger-and-a-bit-better/

Today we are taking a look at Lenovo’s more spacious mini-PC workstation, the ThinkStation P3 Ultra SFF Gen 2. With multiple PCIe slots, the P3 Ultra seeks to strike a fine balance between size and expandability

The post Lenovo ThinkStation P3 Ultra SFF G2 Review A Bit Bigger and a Bit Better appeared first on ServeTheHome.

ASRock Rack Built an Edge Server Based on NVIDIA’s Thor Industrial SoC

Post Syndicated from Ryan Smith original https://www.servethehome.com/asrock-rack-built-an-edge-server-based-on-nvidias-thor-industrial-soc/

ASRock Rack has developed an unlikely edge server based on NVIDIA’s industrial SoC, Thor. The Blackwell-era chip is being used to power the 2UXGI-THOR, a server aimed at the industrial and medical markets

The post ASRock Rack Built an Edge Server Based on NVIDIA’s Thor Industrial SoC appeared first on ServeTheHome.

Introducing Precursor: detecting agentic behavior with continuous client-side signals

Post Syndicated from Marina Elmore original https://blog.cloudflare.com/introducing-precursor/

Bot mitigation is an adversarial game: attackers adapt, defenders respond, and the cycle continues. At Cloudflare, we stay ahead by combining visibility across our global network with signals from the client-side environment. At the network level, we analyze over 1 trillion requests per day to understand reputation, patterns, and anomalies across more than 20% of the web. On the client side, we’ve pushed detection deeper with Cloudflare Turnstile, which has evolved from a CAPTCHA replacement to a risk-based managed challenge that adapts the amount of friction needed to verify the user is authentic.

Today, Turnstile runs nearly 3 billion times per day on some of the most sensitive endpoints on the Internet, helping verify users at key moments like login, signup, and checkout. This improves protection on the most important areas of customer applications, but still leaves limited visibility into the rest of the application — how humans and bots actually interact across the full user journey.

This is the visibility gap we’re closing today with our launch of Precursor.

Introducing Precursor

Precursor is a client-side, session-based verification system, built with privacy in mind, that uses dynamically injected JavaScript to continuously collect behavioral signals as visitors interact with your application. These signals are processed and incorporated into Cloudflare’s bot protection in real time, allowing us to continuously distinguish human traffic from automated or agentic traffic.

This extends the client-side detections offered by a Challenge to your entire web application. Precursor is an optional complement to Turnstile — both are features of our Enterprise Bot Management.

This user-journey-based detection is powerful because modern automation is increasingly capable of appearing legitimate in short bursts. Bots can execute JavaScript, use real browser environments, and pass individual CAPTCHAs without raising suspicion. What remains difficult to replicate is consistent human behavior over time.

Precursor is built to capture that layer of interaction, turning behavior itself into a reliable signal for detecting fraud and abuse. By evaluating behavior across an entire session, Precursor adds significantly more signal to each decision. This improves detection precision, making it easier to distinguish real users from automation without relying on aggressive Challenges. For legitimate users, Precursor means fewer unnecessary interruptions. For bot developers, it raises the cost of operating automation by requiring them to simulate a full session. This is significantly harder to build, more expensive to maintain, and far less reliable to operate at scale.

To err is human 

When a bot developer tries to make a mouse movement look human, they usually add Gaussian noise or uniform random delays. But human movement isn’t just “noisy,” it is also constrained by physics:

  • Wrist pivot: A human mouse movement is often an arc, limited by the range of the wrist and the rotation of the forearm.

  • Cognitive load: There is a measurable delay between a human seeing a checkbox and clicking it.

  • Hand tremor: Even the steadiest human hand oscillates at a physiological tremor frequency.

Bots, by contrast, often behave in ways that give them away. They move in linear interpolations or mathematically ideal Bézier curves. They click with a precision that humans could never replicate. And even when they do manage to simulate human error, there is a rhythm to human movements that can only be seen by examining an entire session.

Mouse movement is just one example of the signals Precursor evaluates, but it illustrates the difference clearly. Below is an example of a mouse automation library interacting with a site. You can see how the mouse moves in perfectly straight lines, always returns to an origin, and reacts with the same velocity. 

Now, contrast that with a human navigating the same site: you see irregular paths, small corrections and overshoots, and variations in speed, timing, and direction. 

Individually, these interactions might look plausible. But over the course of a session, these patterns diverge in ways that are difficult to fake. Precursor is designed to capture and evaluate these behavioral signatures as they develop over a visitor’s interaction with an application.

How Precursor works

To evaluate behavior over time, Precursor continuously collects interaction data on the client and builds a session-level view of activity for that site.

1. Injection and collection layer

When Precursor is enabled on your application, Cloudflare automatically injects a lightweight script into HTML responses from your site as they pass through our network, with no additional configuration, network connections, or third-party embedding required. The injected Precursor bundle is compact, obfuscated, and assembled dynamically for each response. The bundle is designed to not interfere with any additional page logic of the hosted web application.

The script attaches lightweight event listeners to capture interaction signals such as pointer movement, keyboard activity, focus changes, and visibility. These events are serialized into a compact format and buffered in memory. At regular intervals, the buffered data is sent back to the evaluation layer for analysis.

2. Evaluation layer

On the edge server, incoming Precursor payloads are deserialized into behavioral inputs. A dispatcher runs a roster of evaluators on the input data. Each evaluator reads the Precursor streams it cares about and can raise signals into the shared detection registry.

Evaluators are designed to cross-reference data. For example, they confirm that pointer activity correlates with page visibility duration, or that keyboard events only fire when a text field is focused. This stream of information is then consolidated into individual signals that are used for weighting detections.

3. Session integration

Precursor data is session-scoped, meaning it accumulates throughout a session. Session scoping is important because it means a bot cannot reset its behavioral signature by refreshing the page or starting over with a new challenge. The system also feeds session metadata into downstream detection layers for additional shadow-mode heuristics and session analysis, predicted vs. actual completion, and session delinquency heuristics. These edge-side observations are logged for detection improvement purposes and to adjust the bot score of a session. 

4. Privacy by design

Precursor was designed to collect signals that help to distinguish human patterns from automated and abusive patterns.

The event listeners capture the minimum information needed to be a useful signal for detecting automation and abuse. For example, keyboard activity is captured as timing and rhythm, not as the actual keys pressed. In addition, behavioral signals are evaluated as aggregate patterns rather than individual actions and are consumed internally by Cloudflare’s bot detection systems; they are not exposed to customer dashboards or tied to user accounts, login identities, or persistent profiles.

Taken together, this allows Precursor to maintain a continuously evolving evaluation of behavior, maximizing precision while minimizing the friction on good users.

Per-session analytics

To support this new layer of detection, we are introducing session-based views in Security Analytics. These dashboards shift the perspective from individual requests to full visitor journeys. You can now answer questions like:

  1. What does a typical session look like on my site?

  2. Where do sessions diverge from expected behavior?

  3. Which sessions show signs of automation over time?


Use Security Analytics to explore session-based views for your bot management traffic.

These analytics now capture information that per-request analytics can’t —  especially the behavior that occurs between requests. Precursor feeds directly into existing systems like bot score, challenge decisions, and security rules, so you benefit from this added context immediately.

What’s next

Precursor is the foundation for extending bot detection across the entire application. We are continuing to expand the range and depth of behavioral signals for security, how session-level insights influence our bot management protections, and new ways to visualize and act on session data. As bots evolve, detection needs to move beyond isolated checkpoints and into the full flow of user activity.

Get started

Precursor is rolling out now and can be enabled directly from your Cloudflare dashboard. Precursor will be free to use until our GA release later this year. Getting started is simple: turn Precursor on for your zone and choose how strictly you want to verify sessions. You can run it in a low-friction mode to observe behavior in the background, or require a fully verified session by enforcing Challenges if a session doesn’t already exist. 

Once enabled, Precursor begins enhancing your existing bot defenses immediately, with no changes required to your application. If you’re already using Bot Management or Turnstile, Precursor extends those protections beyond Challenges and into the rest of the session. Enable Precursor to extend detection across the full user session, including the activity between moments you already protect.

AI Data Centers and the Concentration of Wealth

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/ai-data-centers-and-the-concentration-of-wealth.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

Opposition to AI data centers has emerged as a primary theme in US politics, one that—surprisingly—doesn’t fall along party lines. We applaud people coming together for constructive debate on any issue, and agree that communities need to evaluate whether any economic benefits these data centers bring is worth their costs. Still, we worry that a focus on data centers obscures the larger impacts of AI on people’s lives: the concentration of power of AI companies, and their widespread political and financial influence.

Local data center opposition is grounded in legitimate concerns about misallocation of land resources when housing is at a premium, pressures on already higher energy prices, and localized environmental impact. Unlike other resource-consuming and polluting industrial facilities, data centers produce very few jobs. The fact that US opposition to data centers seems to be most fierce among lower-income communities reflects righteous indignation with an inequitable bargain, where tech companies and developers profit from exploiting local resources but offer little in return. On a global scale, their carbon footprint could grow unsustainably if usage accelerates. And all this is in aid of a technology that many fear will propagate misinformation, take their jobs, or even cause existential risks for humanity.

For some, data center opposition may feel like the only tangible mechanism for registering their concern, disapproval, or even anger about AI. The problem is that this may be exactly what the AI companies are banking on. They can overcome the protest when it matters to them, and live with a significant fraction of proposals being defeated. More importantly, focusing political opponents on the data center issue obscures the bigger prize they’re after.

While there is a staggering three-quarters of a trillion dollars being spent on data center infrastructure by US companies this year alone, this investment should be taken in perspective. The market for enterprise software, for example, is about twice this size. And it’s small compared with what these companies actually want.

AI companies have their eyes set on capturing all the value created by entire industries. The technology has arguably already conquered customer service and consumer sales. But on the horizon are bigger targets, such as enterprise software development, creative design, management and even legal services. In AI companies and their allies’ vision of the future, AI replaces teachers and doctors. The companies would rather spend time fighting resistance to how fast they are building computing infrastructure than dealing with issues of how their products should be used in those fields, or how those fields should be protected from their products.

And while data center opposition campaigns have been successful in building widespread appeal, their effectiveness in the US is mixed. They seem to be most successful when organizing against speculative, early-stage data center proposals that have a relatively low likelihood to ever see fruition. Meanwhile, advanced-stage, well-capitalized data center projects have proven to have the resources to overcome local opposition. An OpenAI- and Oracle-backed facility in Saline township, Michigan, is breaking ground on construction even after local officials voted to reject it. The developers sued the town of 3,000 and forced a settlement that involved their project going forward. Meanwhile, the Trump administration, a vigorous ally of corporate AI, has signaled its willingness to advance AI infrastructure development by overriding state objections and even using federal lands.

Also consider that rampant data center development may be a momentary spike rather than a longstanding concern. Demand for the centralized computing that data centers provide may well decline over time. The leading Chinese labs, such as Z.ai, are innovating in technical mechanisms to make frontier-class models smaller and cheaper to run. AI power users have become adept at miniaturizing open weight models, ones published free for anyone to download and use, to run locally on their own computers. Apple and Google both support infrastructure stacks for running AI models directly on mobile phones. It could be that the current mania for data centers will look like the fiber optic cable bubble from the early 2000s, as demand shifts to smaller models and AI usage on people’s own devices.

For those concerned primarily with affordability and environmental protection, singling out data center construction is misplaced. Energy rates and inflation today seem to be most visibly affected by the US-Iran war. The US is disinvesting in long-term energy security by ceding the renewable energy industry to China and actively cancelling climate commitments. Consider that 10% of global carbon emissions stem from heating buildings, which dwarfs energy use by AI and could be cut fivefold by using heat pumps powered by renewable energy. With respect to housing affordability, federal housing subsidies have changed little over three decades, in inflation-adjusted terms, even as housing costs have spiked and homeowners have enjoyed robust tax incentives.

As for AI itself, the concentration of power and wealth in these tech companies is the greatest existential risk facing society today. This means we must limit corporate power, especially corporations’ ability to exploit the public and manipulate our political system.

Opposing data centers should be just a starting point. We can advocate for states to regulate AI, to reject irresponsible uses of the technology, and shape corporate behavior. We can fight for AI computation to be taxed, so that the public can capture some of the profit of AI use while also forcing AI companies to internalize more of the energy and environmental consequences associated with its use. And we all can join the global movement for Public AI, an alternative ecosystem for AI that is developed under public control with an incentive structure to create public benefit rather than private profit.

The US midterm elections present ample opportunity for those seeking to control the AI political agenda. In the recent New York congressional Democratic primary, PACs linked to the dueling AI companies Anthropic and OpenAI spent millions of dollars lobbying for or against “AI safety“, the idea that we must urgently monitor and prevent people from using AI to cause catastrophic harms. We’re already seeing a similar dynamic play out in races in Massachusetts and other states.

Why would Anthropic and OpenAI—bitter industry rivals but fundamentally on the same side politically—support opposing viewpoints? Because they both ultimately profit from the mystique: the idea that their products are so powerful that controlling those products is the world’s most important challenge. Here’s the typical read on the dynamic. To one side (backed by OpenAI affiliates), “safety” comes from the appearance of US industry dominating AI innovation, under the slow-moving control of federal lawmakers (and without pesky state regulators in the way). To the other side (backed by Anthropic), “safety” means a heavier regulatory framework that plays to Anthropic’s posturing as the ethics- and compliance-focused AI vendor. In both cases, it’s more marketing than principled concern about safety.

Political organizers should call out and reject the AI companies’ framing of the debate, and reorient campaign agendas around populist resistance to corporate concentration of wealth and power. When AI companies pump millions into legislative races, the result should not be hyperbolic discussion of AI superintelligence. And when a plot of land in a small town is pitched as a data center site, the debate should be about more than the local costs and benefits. It should include out-of-control money in politics, and Citizens United-proof solutions to limit corporate influence like public financing and state regulation.

We all have a vested interest in what’s on the policy agenda, and what the outcomes are. Today, the greatest risk AI poses to society is the exacerbation of inequality and the concentration of wealth. The real problem is trillion-dollar AI companies and their trillionaire oligarchs cozying up to political power in Washington and governments worldwide, and using their money to enact their agenda over the popular will of the people. This is the issue we’d like to see put front and center, and it requires solutions much more extensive than slowing data center development.