At Computex 2026, NVIDIA announced that its next-gen Vera Rubin platform is now in full production. The company is also bringing Windows to its high-end DGX Station systems, which will be available in Q4
Abstract: Artificial intelligence is fundamentally reshaping the balance between vulnerability discovery and remediation. Frontier AI models are now capable of autonomously identifying exploitable software vulnerabilities at unprecedented speed and scale. This development exposes decades of accumulated technical debt created by a software industry that prioritized rapid deployment over secure-by-design engineering practices. Drawing on the evolution of software assurance, vulnerability disclosure frameworks, and U.S. cyber policy, this perspective argues that the current moment represents a strategic inflection point for governments, industry, and critical infrastructure operators. The author examines the growing tension between offensive and defensive equities in cyberspace, the emergence of AI-enabled vulnerability discovery capabilities in both the U.S. and China, and the increasing risks posed by unsupported legacy systems and AI-assisted code generation practices. Responsible disclosure can no longer remain a reactive or fragmented process, but must become a coordinated national and international resilience effort involving governments, software vendors, infrastructure operators, and emergency response organizations. The article concludes with an urgent call for accelerated remediation, large-scale patch management coordination, and sustained investment in automated vulnerability repair capabilities before adversaries exploit this rapidly narrowing window of opportunity.
Fresh out of Computex, NVIDIA has introduced its long-awaited Arm SoC for Windows PCs, the RTX Spark. With 20 CPU cores and a sizable Blackwell GPU, NVIDIA is setting their sights on powering the premium Windows market
The second keynote of Computex 2026, Qualcomm’s CEO Cristiano Amon is at the show to talk about agentic AI, consumer PCs, and more. Come join ServeTheHome for our live blog coverage of the keynote
Computex 2026 kicks off with NVIDIA’s keynote. CEO Jensen Huang is taking the stage for two hours to discuss AI, PCs, robotics, and all things NVIDIA. Come join ServeTheHome for our live blog coverage of the keynote
Cloudflare processes more than a billion events every second. Our network spans 330+ cities in 120+ countries. Behind every HTTP request, every Worker invocation, every R2 read operation, there is data, and a lot of it.
For years, that data was not very easy to access. It lived in dozens of production databases, ClickHouse clusters, Kafka streams, Google Cloud buckets, BigQuery datasets, and a long tail of pipelines. To answer a simple question like “How many domains that signed up today are in the Top 100 by traffic?”, an analyst at Cloudflare had to know which system to ask, what credentials to use, what query language to write, and whether the data they were looking at was sampled, fresh, or seven-days stale. As a result, it was difficult to glean informed insights from the data.
To solve this problem, we built two in-house tools: Town Lake, Cloudflare’s unified data analytics platform, and Skipper, an AI data agent that runs on top of it. Town Lake is a single SQL interface to everything Cloudflare knows, and Skipper is how anyone at Cloudflare can ask questions in plain English and get correct, auditable answers back in seconds.
This is the story of how we built both.
The shape of the problem
If you have ever worked at a company that went through a hyper-growth period, you know what data sprawl looks like. Ours had a few specific symptoms:
Too many disparate systems. A product engineer who wanted to investigate a customer issue might need to query Postgres for account metadata, ClickHouse for analytics events, BigQuery for usage rollups, R2 for raw logs, and Kafka topics for real-time signals. Each system had its own credentials, its own language, and its own retention policy.
Sampled data. This is fine for dashboards, but doesn’t work for domains like billing. Our analytics pipeline downsamples to handle 700M+ events per second. That is the right behavior when you want an analytics dashboard to load, but it’s exactly the wrong behavior when you are trying to compute someone’s usage required to issue an invoice.
External dependencies for internal data. Parts of our previous internal reporting stack were powered by external vendors. Beyond the cost, we had a hard external dependency on another cloud for some of our critical data.
No one could find the data. Even if you had all the right credentials, you needed to know that the right table for “Billable Workers requests by account” lived in a specific ClickHouse cluster, in a specific schema, joined to a specific Postgres dimension table, and that the join required an obscure customer ID translation. There was too much tribal knowledge.
We had a cultural challenge too: data infrastructure had historically been treated as a back-office function that was in service of the business, rather than critical infrastructure in its own right.
What we wanted
We wanted to create one place where anyone at the company with appropriate permissions and a need to know could get answers to questions about Cloudflare: “Show me the top 100 customers by revenue in the last quarter”, “List all Bot Management ML scoring events with score > 0.9 in the last 48 hours coming from a specific ASN”, “Find the Top 100 billing support tickets from customers who have spent >$100”, etc.
We wanted that place to give fresh, accurate, unsampled data for the queries that need it (like billing or security investigations) and fast, downsampled data for the queries that don’t (like dashboards or exploration).
We wanted security and governance baked in, with personally identifiable information (PII) detected automatically, and sensitive tables locked down by default. All access should be auditable, and have time-bounded permission grants so that users could only access data when they were actively working on tasks that required it.
We wanted it to be built on Cloudflare’s own platform: R2 for storage, Workers for compute, Cloudflare Access for authentication, Workflows for orchestration. If we were going to make a major investment in our data infrastructure, it was going to be built on the same products we sell to customers.
And we wanted, eventually, an interface that did not require knowing any SQL. The goal was to empower anyone at the company with appropriate permissions and a need to know to look at the stream of data flowing through our network, not just analysts.
That last requirement is what became Skipper.
Town Lake, the platform
At its core, our data platform’s architecture is a data lakehouse: a query engine that reads from object storage, with a metadata layer that makes the storage behave like a database. We call it Town Lake, after its namesake in Austin, Texas.
Its most important components are:
Query engine. We chose Apache Trino for that: a single SQL query can join a Postgres table, a ClickHouse table, and an Iceberg table on R2 without a need to materialize the intermediate results into a different system. A query that asks “what are the top 100 paying customers by Workers requests this week” compiles into a plan that pushes filters into ClickHouse, joins against an account dimension in Postgres, and ranks against billing rollups in R2, all in one go.
R2 Data Catalog, our managed Apache Iceberg service, is where the cold and warm data lives. Iceberg gives us schema evolution, time travel, partition evolution, and the ability to compact data as it ages. Per-minute usage from last week becomes hourly, hourly from last quarter becomes daily, etc. The storage cost decreases as recency does, while the data stays queryable. Parquet files in R2 are much cheaper compared to keeping the same data in an OLAP database.
DataHub is our metadata catalog. Every table, column, owner, lineage edge, and glossary term lives there. When a user asks “what’s in townlake.dim.accounts,” DataHub provides an answer, including the table description, the column descriptions, the owning team, the upstream tables that feed it, and the downstream tables that consume it.
Lifeguard is our access control service: it stores access rules in D1, dynamically pulls user and group membership from our internal access management system, and renders a combined JSON policy that Trino reads over HTTP. Lifeguard also feeds basic access information to Skipper and the Gateway, so users get blocked at the front door rather than at query time.
Skimmer is a PII detection scanner. It runs continuously, samples rows from every column in every table, and uses Workers AI to classify whether each column contains PII. It does this in two passes: first, a fast per-column classifier; then, if anything is flagged, an agentic second pass that gets full table context and can query Trino directly to verify. Findings flow into DataHub and into Lifeguard’s allowlist to allow human-in-the-loop review.
Transformer is our ELT (extract, load, transform) engine built on Workflows. Users define a Directed Acyclic Graph (DAG) of SQL transformations with YAML frontmatter (target table, materialization mode, dependencies, schedule). Transformer compiles the graph and runs it on Trino, with state managed by Durable Objects, definitions stored in R2, and run history in D1.
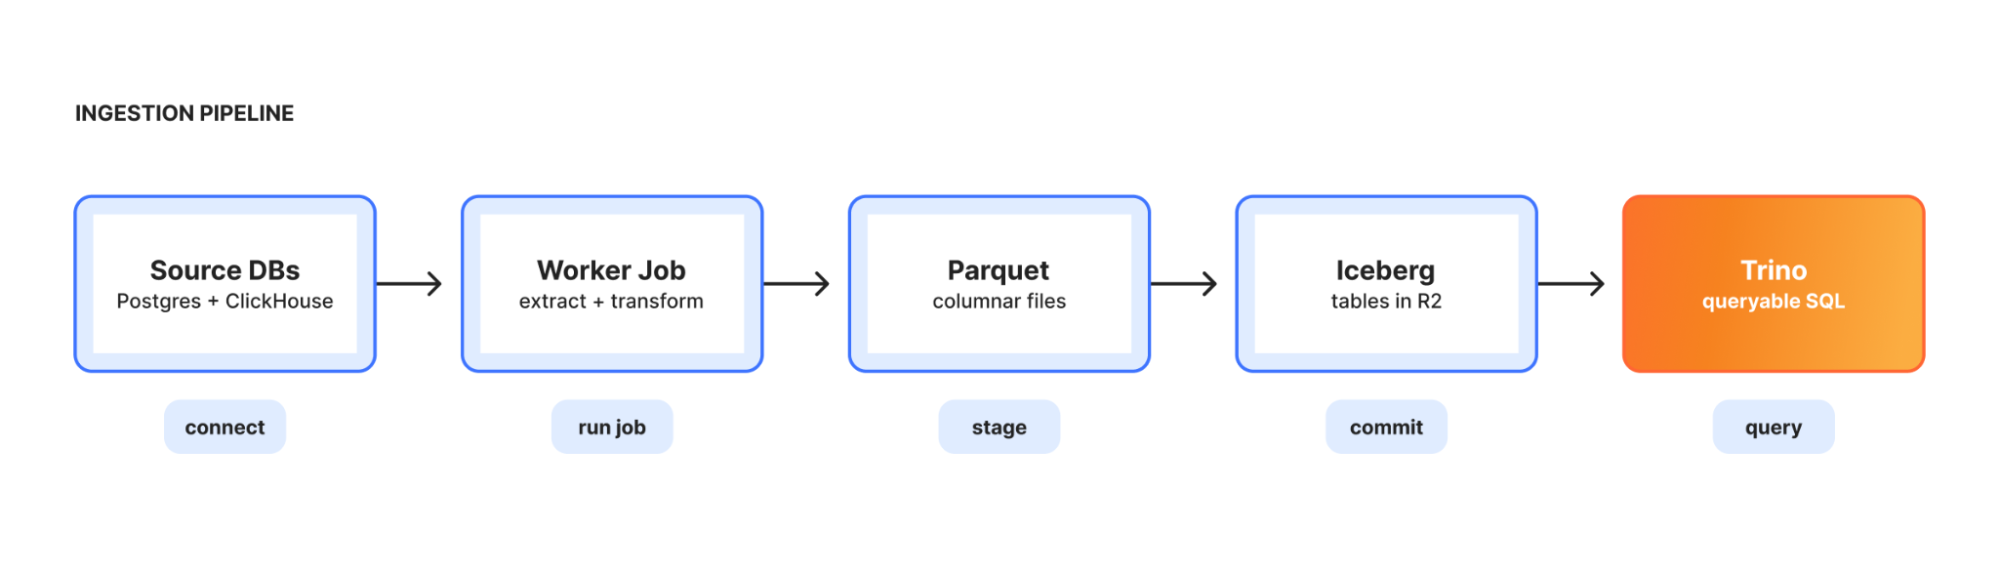
Ingestion is the bridge from operational systems into the lake. An orchestrator runs as a long-lived Kubernetes deployment, reads pipeline configs, and spawns short-lived worker jobs to extract from Postgres or ClickHouse, transform to Parquet, and load into R2 as Iceberg tables. Each pipeline runs as either full-replace or incremental-append.
Default-closed: governance by construction
A real concern when you build a unified data platform is that you have just built a large sensitive-data surface. The traditional answer to this is: open by default, restrict by exception. Allow access to everything, then audit and lock down sensitive tables when someone notices.
Town Lake takes the opposite approach. Tables are inaccessible for querying until they have been reviewed. When a new database is connected to Trino or a new table is created, Skimmer scans it, classifies its columns, and registers it in the central allowlist as pending. Until a reviewer approves the table, and the specific columns within it, users can’t query it. This sounds painful, and it would be, except for two things.
First, it’s automated. Skimmer’s classifier is reasonably good: it catches obvious PII (emails, IPs, names, phone numbers) and the long tail of non-obvious sensitive data (API tokens that match certain prefixes, opaque IDs that can be traced back to users). Reviewers see what was detected and either approve, override, or deny. Most reviews take seconds.
Second, the workflow is self-serve. If you query a table you don’t have access to, the error message is not “permission denied.” It’s “this table needs review, click here to request one.” Skipper, the AI agent, will even suggest the right RBAC group to request and link you straight to it.
We separate schema discovery from data access. Users can see what tables exist, but unreviewed columns are hidden from DESCRIBE and SHOW COLUMNS and from SELECT *. That subtle distinction matters: it means a new unreviewed column doesn’t break existing dashboards built on the rest of an approved table.
PII is opt-in per session. By default, Trino redacts sensitive columns before they ever hit your screen. If you have a legitimate need for raw PII (e.g., fraud investigation), you flip the bit on the session, your permissions are checked, and the redaction is lifted. The flip and every query is logged.
Skipper: the AI data agent
A query engine alone isn’t enough these days. SQL is still a barrier, as is knowing which of tens of thousands of tables to query — you need to know the canonical schema.
Skipper is our take on a conversational AI agent that goes from natural-language question to validated answer, grounded in the company’s actual data, code, and institutional knowledge. We built it on top of Town Lake and on top of our developer platform: Workers, Workers AI, Durable Objects, D1, R2, Workflows, KV.
The interface is a chat box. Ask a question:
Show me the top 10 customers by R2 storage cost in the last 30 days, and the change versus the previous 30 days.
Skipper finds the right tables (DataHub search), pulls their schemas and lineage, writes the SQL, submits it to Trino, polls for results, and shows you a table or a chart. Follow up:
Now break it down by region, and ignore internal Cloudflare accounts.
It carries the context, refines the query, and reruns it. If something looks wrong, e.g., a join produced zero rows or a filter excluded what you expected, then Skipper investigates, adjusts, and tries again, in the closed-loop reasoning. The hard part was having the right context.
Skipper can also package charts into dashboards that can be shared internally and embedded into other internal applications. It also has tools for building transformation graphs via Transformer and for checking access and permissions via Lifeguard.
Skipper meets its users wherever they are. All of these tools are available via a Worker backed by a built-in agentic harness powered by Workers AI. On the flip side, many of our internal users work via local agentic flows, and Skipper’s tools are additionally available via an MCP server.
Layers of context
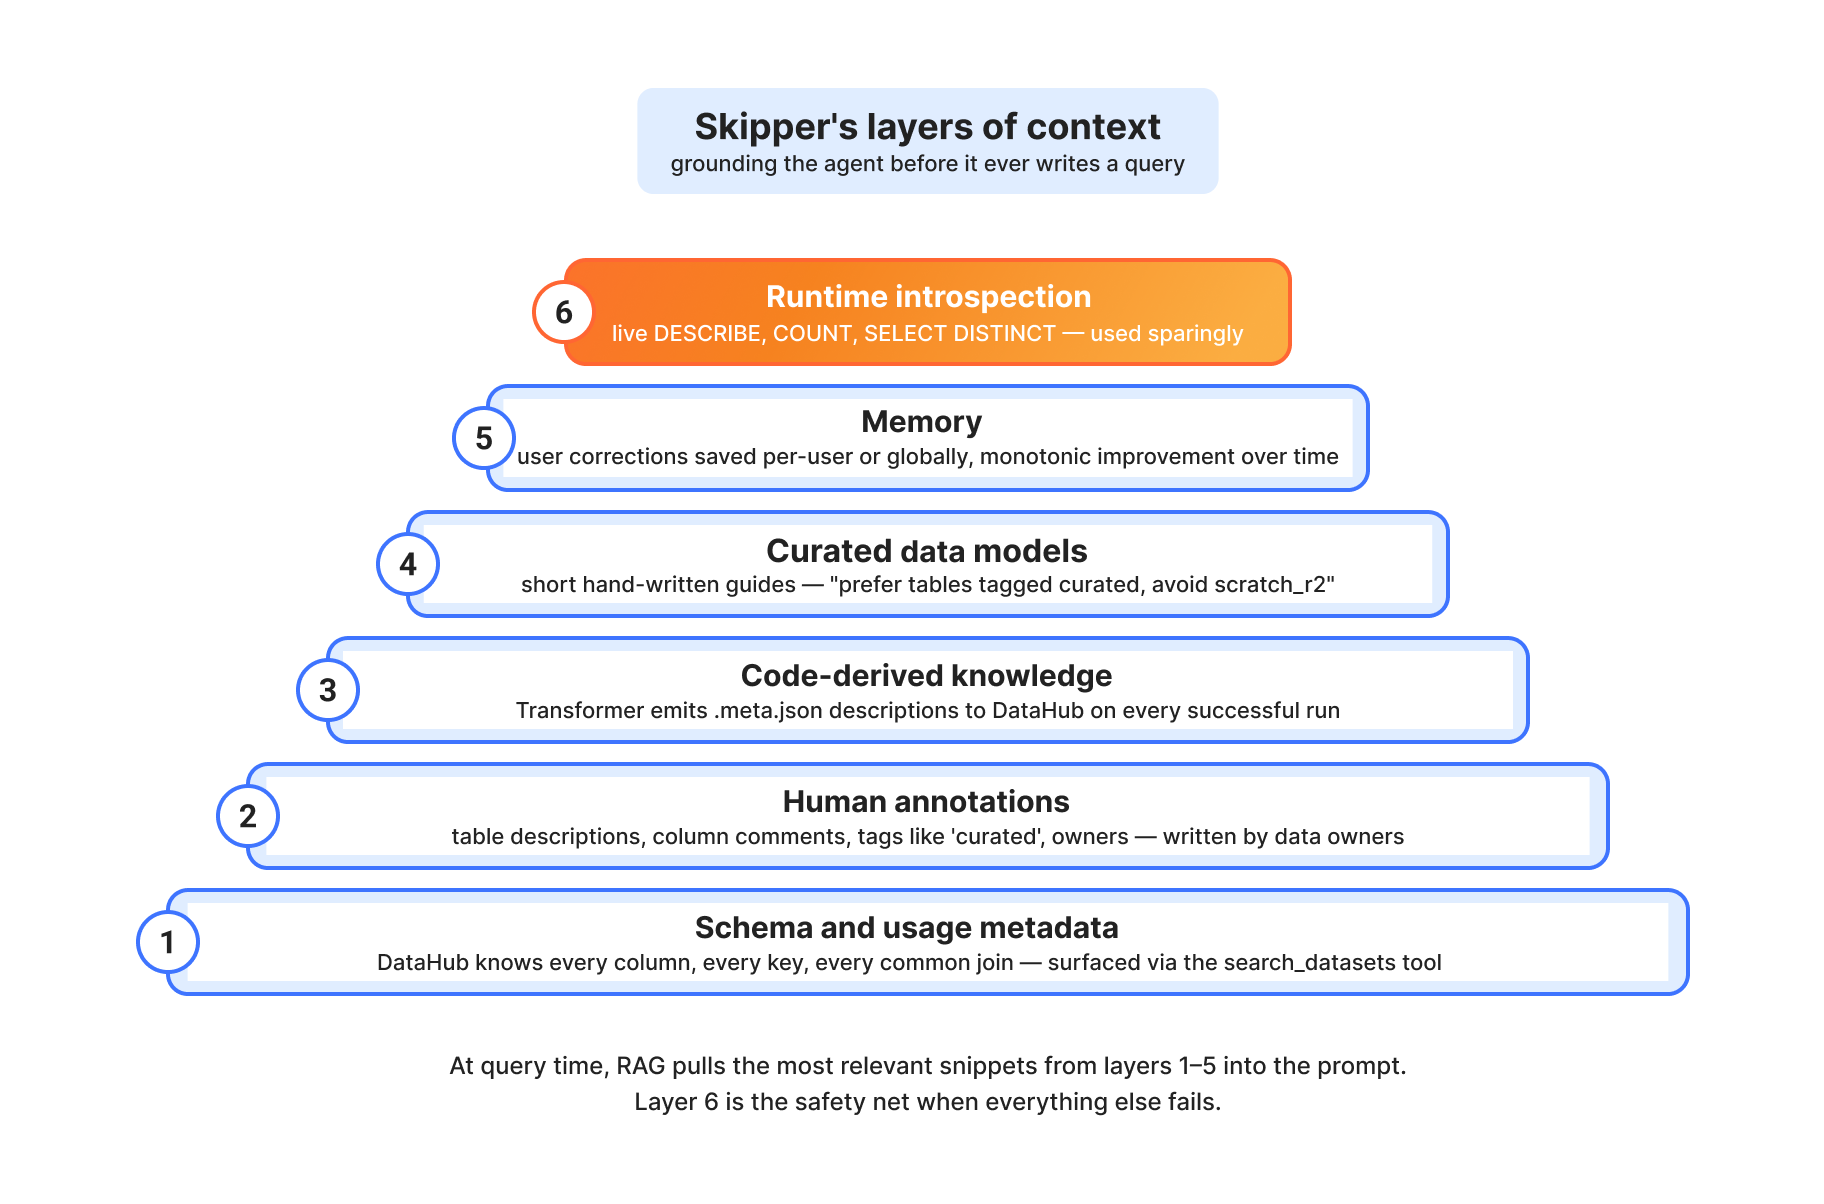
An LLM, given a SQL prompt and a list of table names, can hallucinate joins, misuse columns, and confidently produce a number that is completely wrong. We learned this the hard way during early experiments. The fix is multiple layers of grounded context that the model can pull from at retrieval time.
Layer 1: Schema and usage metadata. DataHub knows every column, every type, every primary key, every foreign key for every table. It also knows which tables are commonly joined together based on historical query patterns. Skipper’s search_datasets and get_entity_details tools surface this directly.
Layer 2: Human annotations. When the team that owns dim.accounts writes a description like “Account-level entity. One row per account_id. Every account belongs to exactly one customer (via customer_id FK),” that description lives in DataHub and ends up in Skipper’s context. Tags like curated mark validated tables that Skipper should prefer over scratch space.
Layer 3: Code-derived knowledge. Some of the most valuable context is not in any catalog: it’s in the SQL that produces the table. The Transformer pipeline emits per-node .meta.json documentation to DataHub on every successful run. So when Skipper looks at fct.billings_allocated, it doesn’t just see the schema; it sees that this is a pre-joined fact table built from dim.accounts, dim.customers, and seed.product_classification, with its alloc_amount column computed as billed_amount / 12 for annual; billed_amount for monthly. That’s the kind of nuance that separates a correct answer from a confidently wrong one.
Layer 4: Curated data models. We maintain a small set of “data model” pages: short, human-written documents that describe how to think about billing, customers, accounts, and zones. “Prefer tables tagged ‘curated’. Avoid scratch_r2 and tables tagged ‘internal’. Search with data model terms (e.g., ‘billing product revenue’) not natural language.” These are surfaced as MCP resources that the agent can pull when the question matches.
Layer 5: Runtime introspection. When everything else fails, Skipper can issue live queries to Trino: DESCRIBE table, SELECT DISTINCT col LIMIT 20, SELECT COUNT(*). It uses these sparingly as runtime context is expensive, but it’s the safety net that makes the rest of the system robust.
Skipper as MCP: Code Mode
One specific implementation detail is worth pulling out, because it is uniquely a Cloudflare-shaped solution.
When you build an AI agent with tools, the standard pattern is to define the tools in your prompt, let the model call them one at a time, parse the response, execute, and return results. This is fine, but it is chatty: a five-tool workflow is five model round-trips, each of which has to re-establish context.
For our MCP server, we use Code Mode. Instead of defining 30 individual tools, we expose two: search and execute. The model writes a JavaScript snippet that calls our entire toolset programmatically:
That JavaScript runs in a sandboxed Dynamic Worker isolate via WorkerLoader. The model gets to express complex multi-step workflows in a single round-trip, in a language it already knows extremely well. It’s faster, it’s cheaper, and the workflows it produces are auditable as code.
The security model is the data model
Everything Skipper does runs as the calling user. If you don’t have access to a table, Skipper can’t query it for you. If you ask for PII, your permissions are checked. If a query you save is shared with a teammate, their access is checked at view time, not at save time, because group membership changes.
Shared dashboards have their own twist. They can be embedded in any internal Cloudflare tool with a single placeholder div and a script tag:
The iframe auto-resizes to fit content. Content Security Policy (CSP) frame-ancestors blocks embedding from anywhere outside the corporate domain. Cloudflare Access still gates the iframe contents, so an unauthenticated viewer hits the Access login page in the iframe rather than seeing the data. Non-owner viewers are checked against the underlying tables: if they don’t have access, they get pointed at the right group to request.
What it powers: really fast answers
Billing. This was the original use case. Our Billable Usage Dashboard, the customer-facing dashboard that shows pay-as-you-go users exactly what they owe, is powered by a metering pipeline whose source of truth is a set of Iceberg tables in R2, queried via Trino. The dashboard’s API pulls the same compact (date, account_id, metric_name, usage) rows that the invoicing system uses, so the number on the dashboard matches the number on the bill.
Billing-related queries account for 53% of all queries Town Lake serves: 91,760 queries from 324 distinct Cloudflare employees in a recent measurement period. The 200–300 line legacy SQL queries that used to compute revenue rollups by customer are now five lines.
Business intelligence. The “top 100 customers by revenue” question takes about three seconds in Skipper now. So does “how many domains that signed up today are in the top 100.” So do most of the data-related questions we used to file Jira tickets for.
Security analytics. Our Bot Management team uses Town Lake to query ML scoring events with score > 0.9 in the last 48 hours filtered by ASN and geography. Threat researchers have built their own query toolkit on top of it. Trust & Safety pulls signals to help police abuse.
Customer support. “Find the top 100 billing support tickets from customers who have spent >$100” used to be a multi-day project. Now it’s a Skipper query.
What we have learned
A few things have surprised us.
Less prompting is more. Early versions of Skipper had elaborate, prescriptive system prompts: “First, use search_datasets. Then, use get_entity_details. Then, use list_schema_fields if needed…” Quality went down. The model is good at reasoning about analytical workflows; it doesn’t need to be micromanaged. We replaced the prescriptive prompts with high-level guidance and let the model pick its own path. Results got better.
Tool overlap is poison. We initially exposed every variant of every tool: three different “fetch results” tools, two “search” tools, several “list” tools. The model got confused and called the wrong one. We consolidated. Now fetch_results has a mode parameter (inject / display / both) instead of three separate tools. Every tool has a single reason to exist.
Code, not metadata, captures meaning. The biggest accuracy wins came when we started ingesting the actual SQL that produces a table, not just its schema. A customer_type column with values contract, paygo, free looks identical in either context, but the SQL tells you that customer_type defaults to paygo when Salesforce data is missing. That kind of context never lives in column descriptions.
Memory matters more than we expected. There is a long tail of corrections that look like “you have to filter for X like this” or “ignore tables tagged Y.” Without a memory layer, the agent rediscovers and re-learns these every conversation. With one, it gets monotonically better at the recurring questions a team actually asks.
The boring infrastructure is the hard part. Trino + Iceberg is not new technology. The hard work is in the boring stuff: per-row access control, default-closed table allowlisting, query auditing, time-bound credentials, PII detection, idempotent ingestion, schema evolution. Those are the things that make a data platform safe to actually use.
What’s next
We’re expanding the agent surface. Skipper already integrates as an MCP server into any IDE that supports it. The next step is deeper integration with our own internal chat and ticketing systems, so that “ask the data” becomes the natural first move for anyone debugging an incident, scoping a project, or sanity-checking a hypothesis.
We’re investing heavily in the Transformer pipeline. The goal is for any team at Cloudflare to be able to build a curated dataset with a few SQL files and a .meta.json description, deploy it as a Workflow, get it scheduled and monitored automatically, and have it surface in DataHub and Skipper without any additional work. The idea is self-serve data engineering, with the same shape as self-serve software engineering.
R2 SQL, Cloudflare’s serverless, distributed, analytics query engine, is getting more and more robust by the day. As its feature set expands, we plan to move many parts of Town Lake’s workflow over to it.
The bet we made — that the next breakthrough product comes from someone looking at the data and seeing something nobody else sees — is one we’re still betting on. Town Lake is how we make sure they can find it.
Ahead of June pre-orders, AMD is releasing more information about their forthcoming AI dev box, the Ryzen AI Halo. The AI mini-PC will come pre-loaded with a comprehensive AMD software stack and carry a $3999 price tag
Agents have agency: they adapt and find multiple ways to solve problems. This autonomy creates a fundamental security challenge: the large language model (LLM) at the heart of the agent is non-deterministic, and its decisions can’t be predicted or guaranteed in advance. It can hallucinate harmful actions with complete confidence. It’s vulnerable to prompt injection attacks, where adversaries inject malicious commands through tool responses or user inputs. LLMs don’t robustly differentiate between commands and data, everything is only tokens. For these reasons, if you want defense in depth, you must treat the LLM as an untrusted actor from a security point of view.
The insight is that the LLM can’t affect the external world directly: it has to go through an orchestrator that invokes tools based on the LLM’s output. This is precisely where the controls must be applied. What you need at this boundary is authorization: a decision about whether each tool invocation should be allowed and under what conditions. Consider a customer service agent for an online retailer. Without proper controls, it could process refunds that exceed authorized limits, apply discounts to product categories that should be excluded, or look up one customer’s data while handling another customer’s session.
If you control agents’ access to tools, you can establish a safety envelope within which the agent can operate freely. This differs from two common but unsatisfactory approaches:
Creating hard-coded workflows eliminates uncertainty, but by itself defeats the purpose of using an LLM as the brain of the agent, because you’ve built a traditional application with an LLM interface. And even with this restriction, using LLM outputs at any step can open up the same risks. While it’s a useful technique for well-understood workflows, it’s not sufficient for agents that need to adapt.
Human-in-the-loop provides a safety net for critical operations, and it will always have a role. But relying on it as the main control mechanism sacrifices autonomy and can lead to approval fatigue.
You need agents that are safe and autonomous. This requires an auditable, deterministic enforcement layer that sits outside the agent and tools. Why outside? Because the LLM’s plan is the thing you can’t trust—it can’t be responsible for enforcing its own constraints. Controls at the LLM layer—such as system prompts and training-time alignment—can be bypassed by prompt injection or hallucination. Hard-coded checks in agent or tool code are more robust, but become difficult to audit and manage at scale, especially when security logic is scattered across many tools and services. Centralizing authorization outside both gives you a single checkpoint the LLM can’t circumvent; one that’s auditable and can be verified independently of the application code.
This is where AgentCore Policies come in. Amazon Bedrock AgentCore Gateway sits between the agent and the remote tools it calls. When you associate a Policy with a Gateway, it blocks everything by default. Policies selectively open this boundary by specifying which tool invocations are allowed and under what conditions. This enforcement applies to all tool traffic routed through the Gateway. For this approach to scale, it must be more straightforward to reason about the policies than about the agent’s behavior.
AgentCore policies are expressed in Cedar. Cedar is an open source authorization policy language developed by AWS that has recently joined the Cloud Native Computing Foundation (CNCF). Cedar was designed with exactly these properties: it’s purpose-built for authorization, readable by humans, and analyzable by machines using automated reasoning. This gives enterprises the ability to scale policy definition and enforcement to their AI agents.
How Cedar is used by Amazon Bedrock AgentCore
Amazon Bedrock AgentCore provides the infrastructure to deploy and manage agents at scale. It includes AgentCore Runtime for hosting agents, AgentCore Gateway for managing how agents connect to tools using Model Context Protocol (MCP), and Policy in AgentCore. Policy intercepts all agent traffic through AgentCore gateways and evaluates each request against defined policies in the policy engine before allowing tool access. Cedar powers the policy layer.
AgentCore Policy uses Cedar and its mathematical analysis capabilities at several points in the AgentCore Gateway workflow: the Cedar authorization engine is used at policy evaluation and Cedar Analysis is used during policy authoring, and in the control plane.
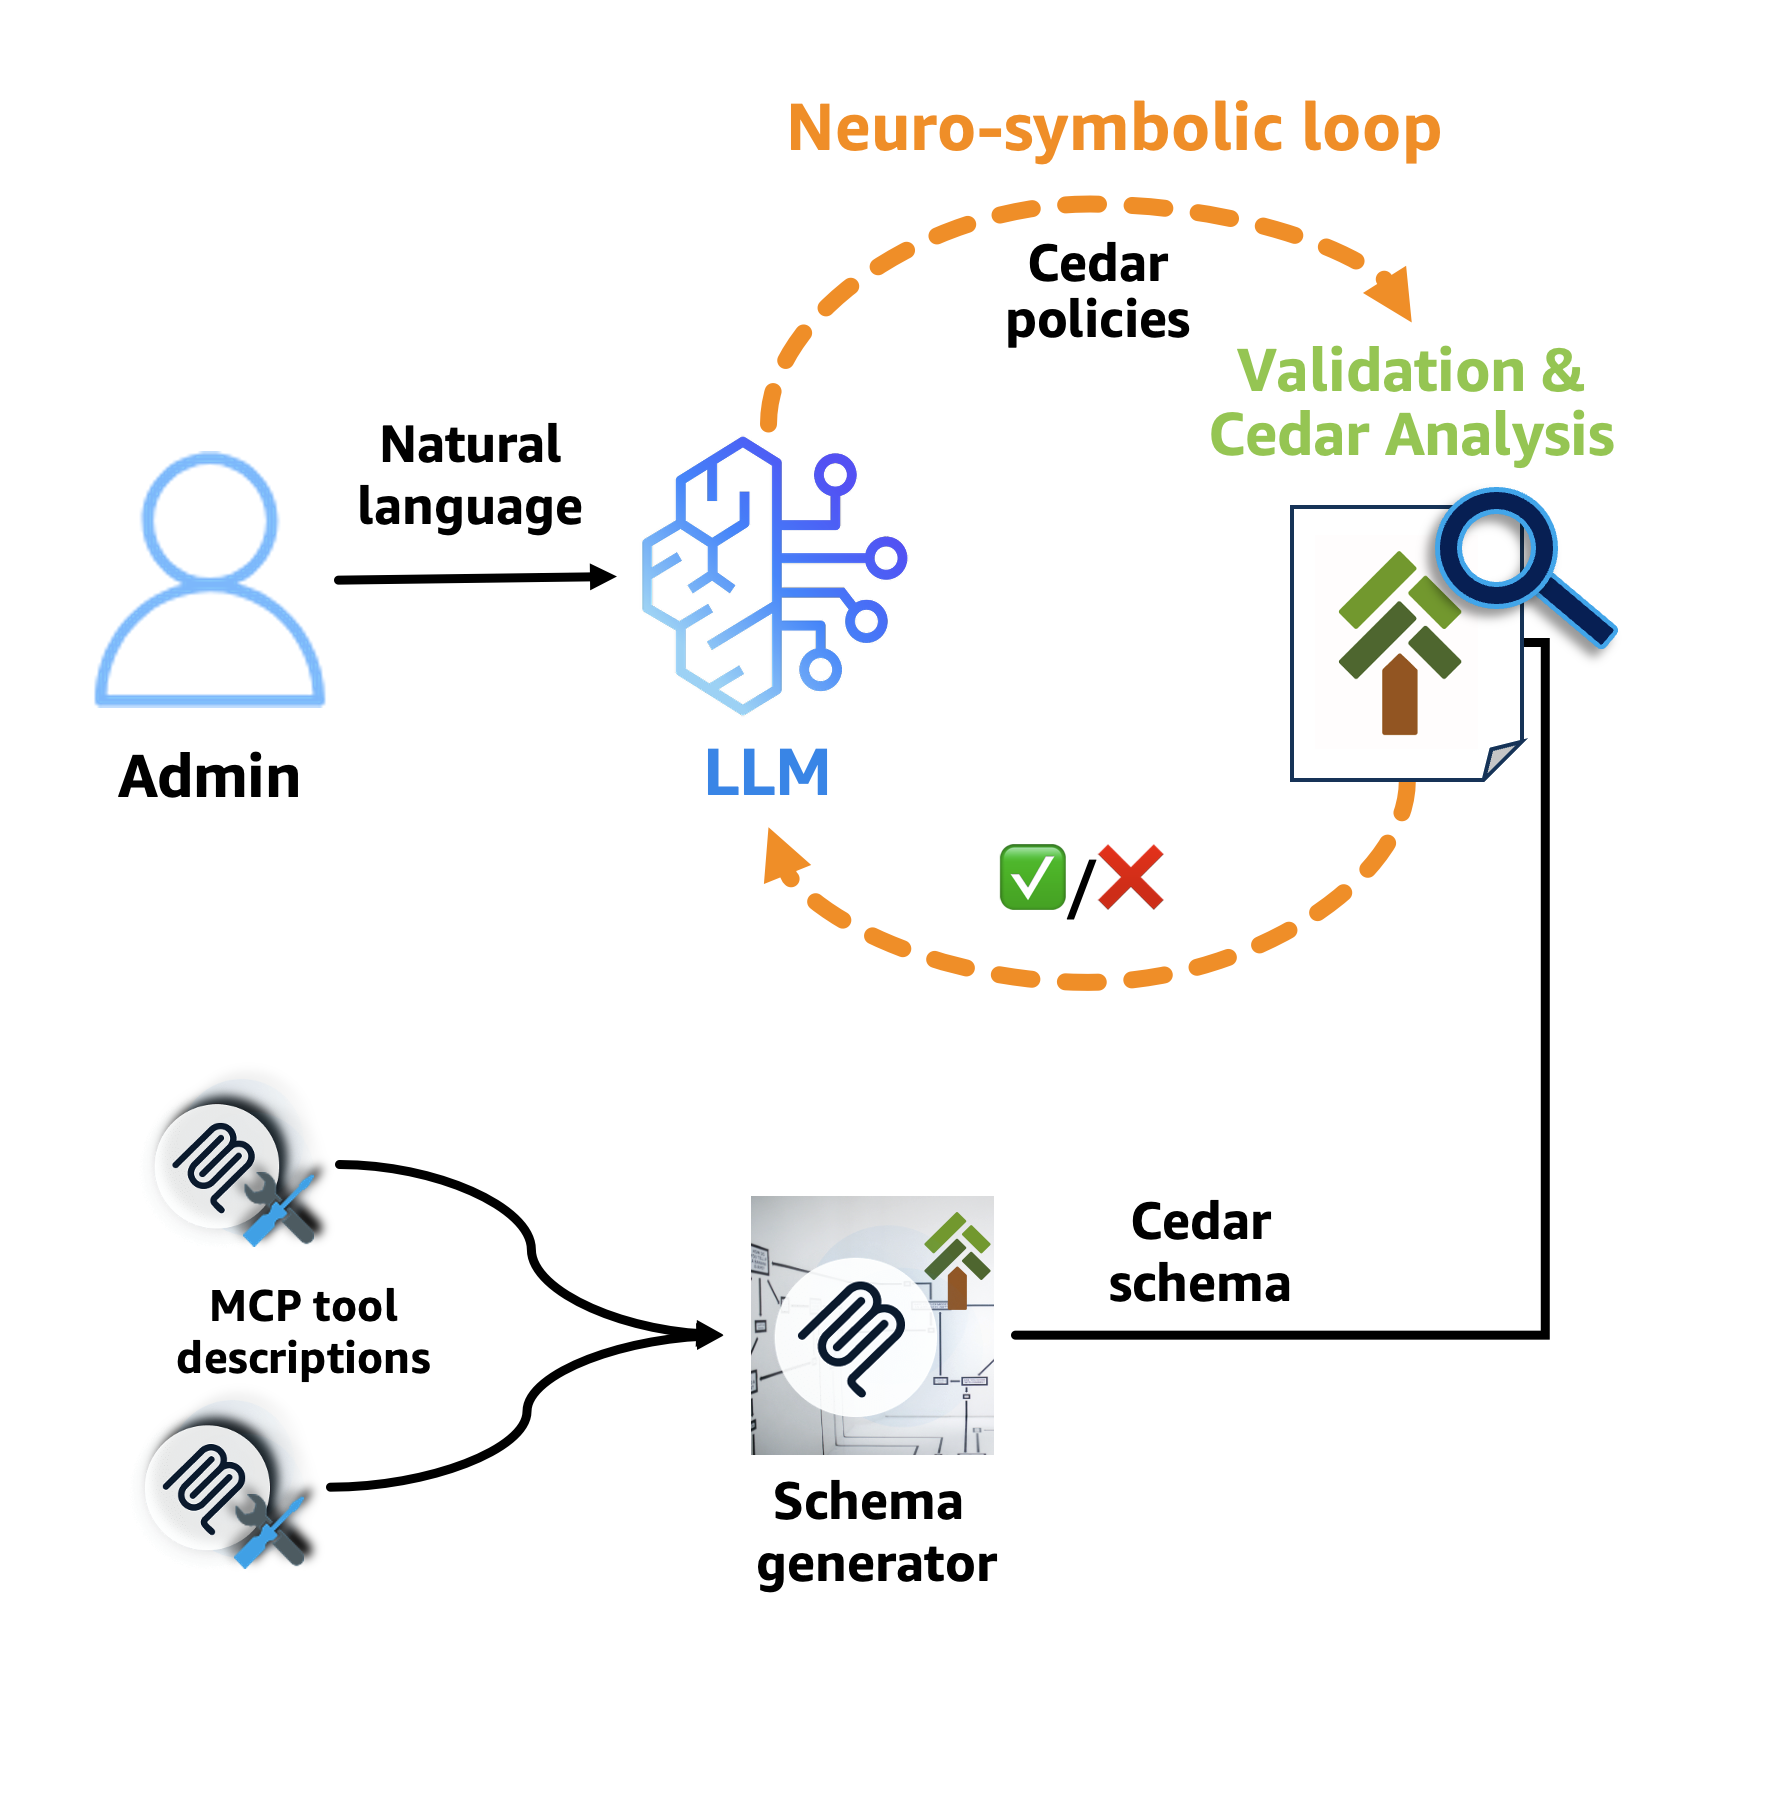
Policy authoring: Developers can write Cedar policies directly or use natural language that gets translated to Cedar through a neuro-symbolic AI feedback loop. Neuro-symbolic AI combines machine learning’s flexibility with automated reasoning’s provable correctness. An LLM generates policies from natural language, while Cedar Analysis validates them using symbolic, mathematical reasoning. The following diagram illustrates this workflow:
Figure 1: Cedar policy generation workflow
An administrator specifies—in natural language—which MCP tools the agent can call and under what conditions. The neuro-symbolic feedback loop then formalizes this description into Cedar policies. Here’s how it works: first, the LLM translates the natural language into Cedar policies. These policies are then run through two stages of verification. In the first stage, AgentCore Policy uses a Cedar schema generator that takes the MCP tool descriptions and produces a Cedar schema. Cedar validates the policies against this schema, helping to ensure that they reference valid tools and parameters and ruling out whole classes of runtime errors. If validation passes, the second stage runs Cedar Analysis, which encodes each policy as a mathematical formula and detects issues like policies that grant or deny everything, or that contain impossible conditions. These mathematical proofs identify errors in the process of translating from the natural language description to Cedar policies, and guide corrections.
The neuro-symbolic feedback loop significantly improves the accuracy of the generated policies. This demonstrates the power of combining neural and symbolic approaches—the LLM provides creative translation from natural language, while automated reasoning provides rigorous validation.
Control plane: When attaching policies to an AgentCore Gateway, Cedar Analysis performs holistic analysis of the entire policy set. Instead of analyzing policies in isolation, it examines how they interact and their combined effect. This analysis identifies potential logical errors—such as conflicting or redundant policies—and detects whether the policy set produces unintended authorization outcomes. When Cedar Analysis detects these errors, the operation fails and returns a description of the issue, so the policy author can fix and retry. See the Formal analysis for policy verification section for examples of the checks.
MCP tool invocation enforcement: Each agent tool request made to the AgentCore gateway is evaluated against Cedar policies which determine whether the MCP tool invocation with the given arguments should be allowed. This creates the safety envelope while allowing the necessary bridges to enable the agent to perform its job.
MCP tool filtering: Cedar enables an additional layer of protection that operates before any tool invocation occurs. When an agent issues a list tools command, AgentCore Gateway uses Cedar’s partial evaluation capability to determine which actions would always be denied under the current policy set. Those actions are omitted from the list tool response. The agent and the underlying LLM never see those tool actions, eliminating an entire class of risk: the agent and LLM can’t attempt to invoke a tool it doesn’t know exists. This is a direct benefit of Cedar’s partial evaluation: the system can determine that certain tool actions are unreachable without needing to wait for an actual tool invocation attempt.
Why Cedar: Analyzability enables safety at scale
Natural language is too ambiguous for security-critical infrastructure, and general-purpose programming languages, like Python, are very expressive but too difficult to analyze. They can have unintended side effects, termination issues, and can be difficult to understand.
Cedar avoids these issues by excluding loops and stateful operations, so policy evaluation terminates in O(n) time in common cases. This bounded execution time means agents can make authorization decisions without disrupting user experience or workflow efficiency.
Cedar is straightforward to read. Regulatory compliance and security audits require policies that humans can understand and verify. Cedar policies read like structured natural language, making them accessible to security teams, compliance officers, and business stakeholders:
// Only allow bulk discounts for premium customers with sufficient quantity
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Platinum" &&
  context.input.orderQuantity >= 50
}
unless
{
  context.input
    .productTypes
    .containsAny
    (
      ["limited_edition", "seasonal_specials"]
    )
};
Auditors without a technical background can understand this policy: “Allow bulk discounts for platinum customers who order at least 50 items, except for limited edition or seasonal special products.” The unless clause makes the exception clear, which is how business rules are typically expressed in natural language. Notice that this single policy constrains two different sources of data. The customer tier comes from a JSON Web Token (JWT) claim—it can’t be hallucinated or manipulated by the LLM. The tool inputs like order quantity and product types, however, originate from the LLM’s tool call. Cedar policies constrain these inputs to only allowed values, ensuring that even if the LLM produces unexpected arguments, the policy enforcement layer rejects them deterministically.
Cedar is the right choice because it’s fast, straightforward to read, and analyzable through automated reasoning. This analyzability is why you can reason about the safety envelope around agents that’s expressed as Cedar policies. As agentic systems grow the number of tools grows. Without proper tooling, policy management becomes intractable; policies can conflict, create security gaps, or produce unintended authorization outcomes.
In the rest of this section, we examine how Cedar’s analyzability directly addresses this challenge through its deterministic, mathematically sound analysis. Because Cedar analysis can reliably detect conflicts and logical errors across large policy sets it enables scalable policy management through neuro-symbolic AI.
Formal analysis for policy verification
Cedar policies can be encoded as mathematical formulas and analyzed using automated reasoning techniques through a symbolic encoder. This enables AgentCore Policy to provide sophisticated policy verification capabilities during policy authoring and beyond. AgentCore Policy uses this analysis when authoring or attaching policies to detect possible logical errors, such as conflicting or redundant policies. Policy analysis, including policy comparison is available as an open source CLI tool. Next, we will take a look at some concrete examples of these checks.
Detecting logical errors in policies: Cedar Analysis can detect when policies contain logical errors. For example, the following policy has contradictory constraints that mean it can’t allow any request: the customer tier can’t be both gold and platinum at the same time. The intention was to use an || instead of &&, a mistake that can be made by both humans and AI systems that author policies.
// This policy cannot allow any requests due to logical errors
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  principal.getTag("customer_tier") == "Platinum"
}
unless { context.input.refundAmount > 1000 };
Similarly, Cedar Analysis can detect policies that always allow a given action, usually an indication of an overly permissive policy. For example, the following policy will allow all ApplyBulkDiscount requests because any order quantity will either be greater than or equal to 100 or less than 100.
// This policy allows all ApplyBulkDiscount requests
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ApplyBulkDiscount",
  resource
)
when
{
  context.input.orderQuantity >= 100 ||
  context.input.orderQuantity < 100 ||
  (principal.hasTag("customer_tier") &&
   principal.getTag("customer_tier") == "Platinum")
};
Detecting such logical errors isn’t easy for humans, and can’t be done by pattern matching: you need the formal rigor of mathematical analysis, which is exactly what Cedar Analysis does.
Detecting policy conflicts: Cedar Analysis can also analyze the entire policy set to detect inconsistencies between different individual policies:
// These policies conflict - Analysis will detect the subtle issue
permit (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  principal.getTag("customer_tier") == "Gold" &&
  context.input.refundAmount < 100
};

forbid (
  principal is AgentCore::OAuthUser,
  action == AgentCore::Action::"ProcessRefund",
  resource
)
when
{
  principal.hasTag("customer_tier") &&
  ["Gold", "Platinum"].contains(principal.getTag("customer_tier")) &&
  context.input.refundAmount < 500
};
The permit policy allows gold customers to process refunds less than $100, while the forbid policy blocks gold customers (and platinum customers) from processing refunds less than $500. Because forbid overrides permit in Cedar, the forbid policy would block all gold customer refunds despite the permit policy.
Comparing policy changes: When updating policies, Cedar Analysis can also determine the exact impact of a change. Consider the following update to the unless clause (the policy lines with + have been added and those with - have been removed): we now block ApplyBulkDiscount only when the product type is limited_editionand the quantity exceeds 200.
 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ProcessRefund",
   resource
 )
 when
 {
   context.input.refundAmount < 500
 };

 permit (
   principal is AgentCore::OAuthUser,
   action == AgentCore::Action::"ApplyBulkDiscount",
   resource
 )
 when
 {
   context.input.orderQuantity >= 50
 }
 unless
 {
-  context.input.productTypes.containsAny(["limited_edition"])
+  context.input.productTypes.containsAny(["limited_edition"]) &&
+  context.input.orderQuantity > 200
 };
At first glance, adding a condition to the unless clause might seem more restrictive. In fact, it’s the opposite: narrowing when the unless applies means the permit now covers more requests. For example, an order of 73 units of a limited_edition product would have been blocked before but is now allowed. Cedar Analysis can automatically detect this and generates the following table showing the difference in permissiveness between the original policy set and the updated one:
Principal type
Action
Resource type
Status
OAuthUser
ProcessRefund
Gateway
Equivalent
OAuthUser
ApplyBulkDiscount
Gateway
More permissive
In the preceding example, the analysis tells us that the updated policy allows allows exactly the same ProcessRefund requests, but allows more ApplyBulkDiscount requests.
This formal verification capability is essential when agents operate autonomously and can affect the real world. Organizations need mathematical certainty that their policies will behave as intended.
Deterministic behavior for reliable governance
Unlike probabilistic AI models, enterprise security requires deterministic guarantees. Cedar policies always produce the same authorization decision for identical requests, regardless of evaluation order or system state. Cedar’s default deny, forbid wins, no ordering semantics help ensure predictable behavior.
// Policy evaluation order does not affect the authorization decision
permit(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.refundAmount < 500
};

forbid(
    principal,
    action == AgentCore::Action::"ProcessRefund",
    resource
) when {
    context.input.orderDate.offset(duration("90d")) < context.system.now
};
Whether the permit or forbid policy is evaluated first, a refund request over $500 will always be denied, and any refund issued more than 90 days after the order date will also be denied. This predictability gives enterprises confidence in their agent governance.
From policies to production
By choosing AgentCore Policy and Cedar, organizations can deploy autonomous agents with policies they can reason about mathematically, not only hope the agents work correctly. Cedar’s combination of expressiveness, readability, and formal verification means that you can design agents with the flexibility needed to function and the certainty security teams demand.
Automated reasoning has already proven its value across AWS, from AWS IAM Access Analyzer verifying access policies to provable security for network configurations. Applying these same techniques to agentic AI is a natural extension: as agents take on more responsibility, the need for mathematically grounded guarantees only grows. The neuro-symbolic approach we’ve described in this post—combining LLM flexibility with the rigor of automated reasoning—points toward a future where agents can be both more autonomous and more trustworthy, because the verification keeps pace with the autonomy.
Executive Summary: Let’s say you wanted to make sure that your AI is secure. Can you just maximize the security and privacy benchmark and call it a day? Nope, because benchmarks don’t actually work for measuring AI capabilities (even when they are NOT emergent systemic properties like security). So let’s take a step back: how do you measure security in the first place? Good question. Over the last 30 years, security engineering for software evolved from black box penetration testing, through whitebox code analysis and architectural risk analysis to de facto process-driven standards like the Building Security In Maturity Model (BSIMM). Software had a very deep impact on business operations, and it appears that AI is going to have an even deeper impact. Will a software security-like measurement move work for AI? Probably. In the meantime we can make real progress in AI security by cleaning up our WHAT piles and managing risk by identifying and applying good assurance processes. (Spoiler alert: no matter what we do, we still don’t get a security meter for AI, so we need to be extra vigilant about security.)
Cloudflare and Anthropic have collaborated to integrate Claude Managed Agents with Cloudflare Sandboxes. Our new integration gives you more control over your agent sandboxes, secures connections to private services, and improves observability.
In the past year, Cloudflare’s Developer Platform has expanded to give more developers the tools they need to run agents at scale. This includes:
Sandboxes for full stateful Linux microVMs at scale
Agents SDK, providing simple and customizable agent framework
Browser Run, which gives agents fully programmable and observable browsers
Dynamic Workers, allowing for dynamic sandboxed code execution at massive scale
Our goal is to make Cloudflare the simplest, most secure, and most programmable cloud for agents.
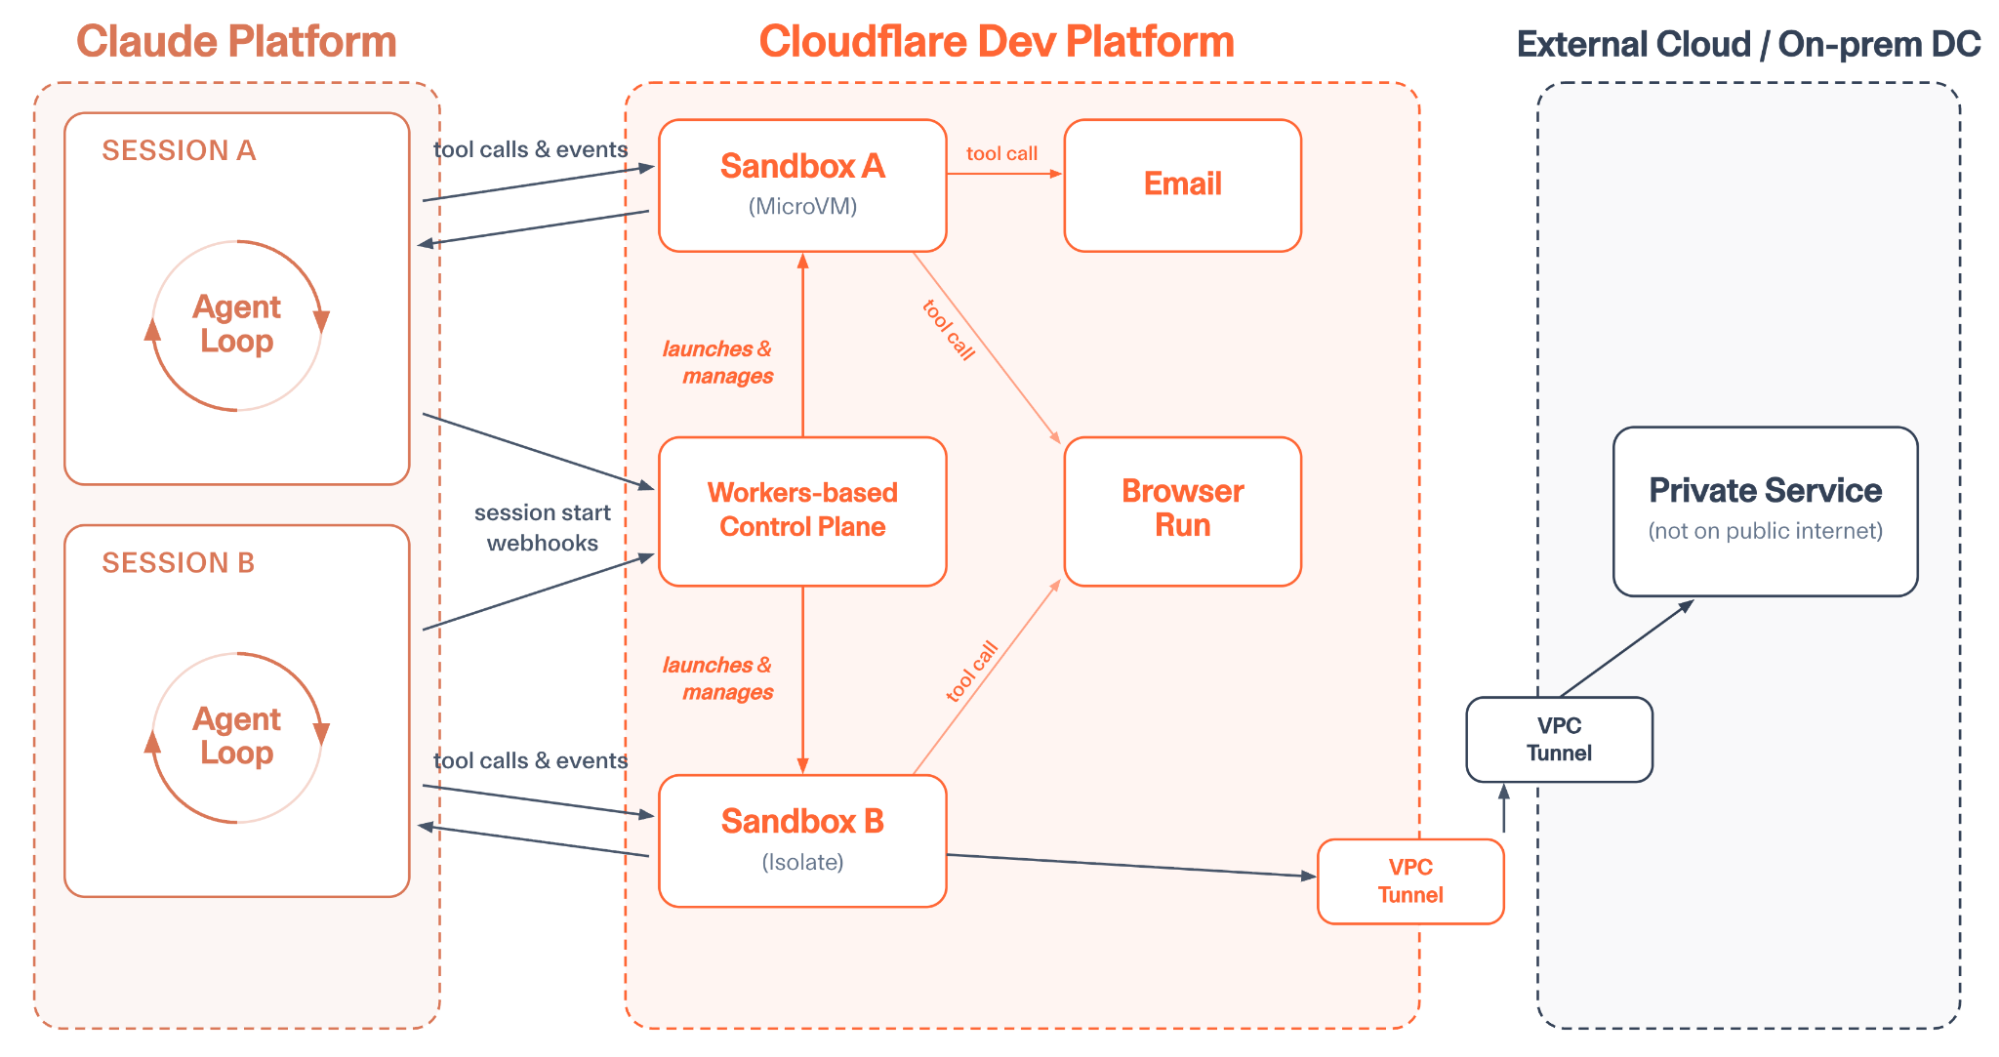
Integrating with Claude Managed Agents is another step in this direction. You can run your agent loop on the Claude Platform, while using Cloudflare to execute code, secure connections, and run custom tool calls.
Enhanced security – Run all agent traffic through customizable proxies. This allows you to securely inject credentials, prevent data exfiltration, and better observe how your agents interact with the outside world.
Sandbox control and observability – Get detailed sandbox metrics and logs. SSH into running machines. Customize sandbox images.
Lightweight sandboxes – Writing and executing untrusted code can be done in a traditional microVM or a lightweight isolate. This lets you hit massive scale, boot sandboxes in milliseconds, and minimize infrastructure spend.
Private service connectivity – Connect agents to private internal services without ever exposing them to the Internet.
Browser Control and Observability – Get an audit trail of every agent’s browser sessions, including session recording and human-in-the-loop flows.
Email – Give each of your agents its own email address and ability to send emails.
Custom tools – Extend your agents with tools without needing additional infrastructure. Just write functions and deploy.
You get all of this out of the box when deploying the integration, and you can easily customize if you need more.
Let’s take a brief look at Claude Managed Agents, see how to integrate a Cloudflare-based environment, then explore how to get the most out of Claude on Cloudflare.
An overview of Claude Managed Agents
Claude Managed Agents allow developers to easily define and run agents on the Anthropic platform. In these managed environments, Claude can read files, run commands, browse the web, and execute code. The harness supports built-in prompt caching, compaction, and various agent-first performance optimizations.
Until now, using Claude Managed Agents has meant running the entire stack on Anthropic-provided infrastructure. While this is great for some developers, others may need more control over their infrastructure choice, whether this is for security, compliance, or performance reasons. Self-managed environments for Claude Agents provide just that.
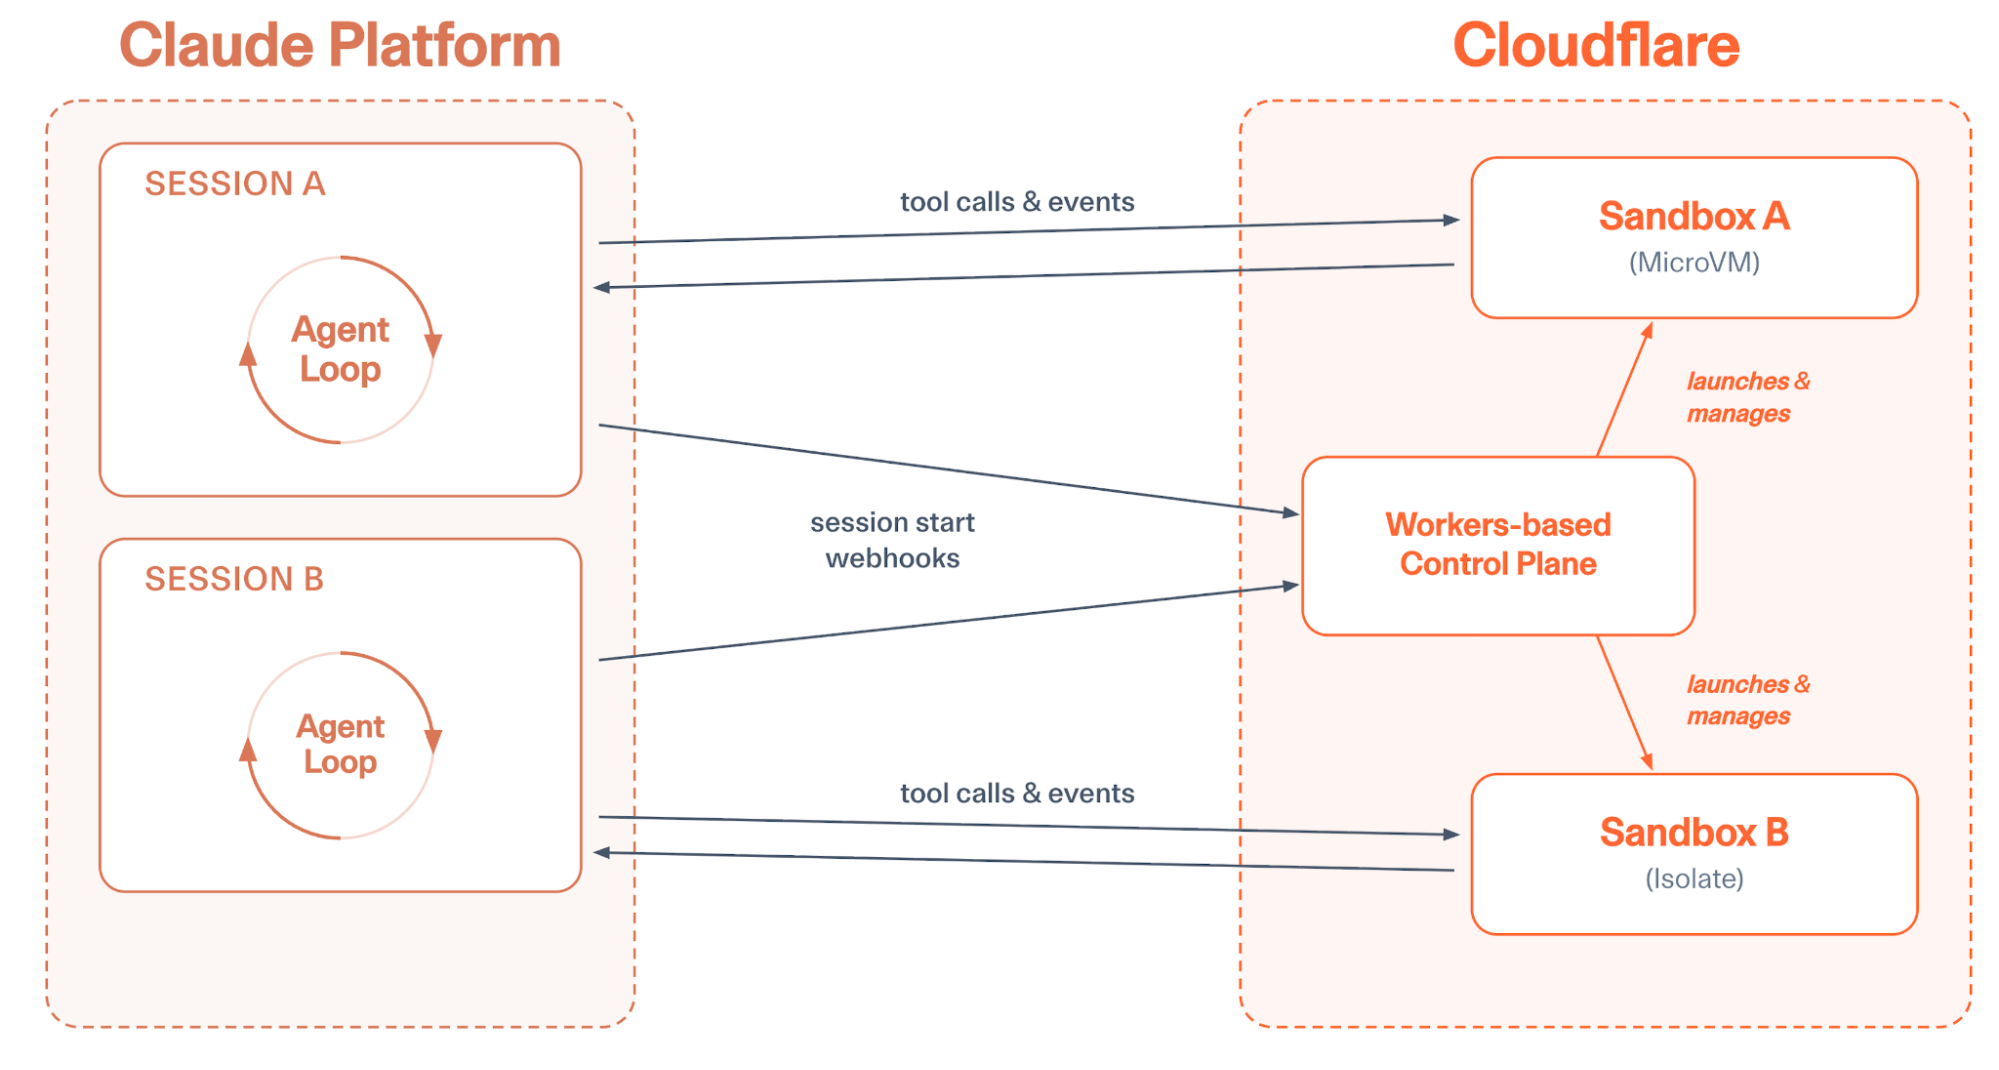
Anthropic describes this as “decoupling the brain from the hands.” The core agent loop runs in Anthropic (the “brain”), but the infrastructure for running and executing code (the “hands”) can be run anywhere, including Cloudflare.
The Cloudflare environment
Our new integration gives your agents a Cloudflare-based environment for running and executing code within minutes.
Follow the onboarding guide to get started. Then fork the repo and customize your integration as you see fit.
After setup, when a Claude Agent starts a session, it sends a message to your new Cloudflare-based control plane. The Workers-based control plane gives each agent session a sandboxed environment for executing code, developing applications, running CLI tools, and more. State is automatically persisted across session sleeps.
Sandboxes write files and execute code in response to the Claude-based Agent loop
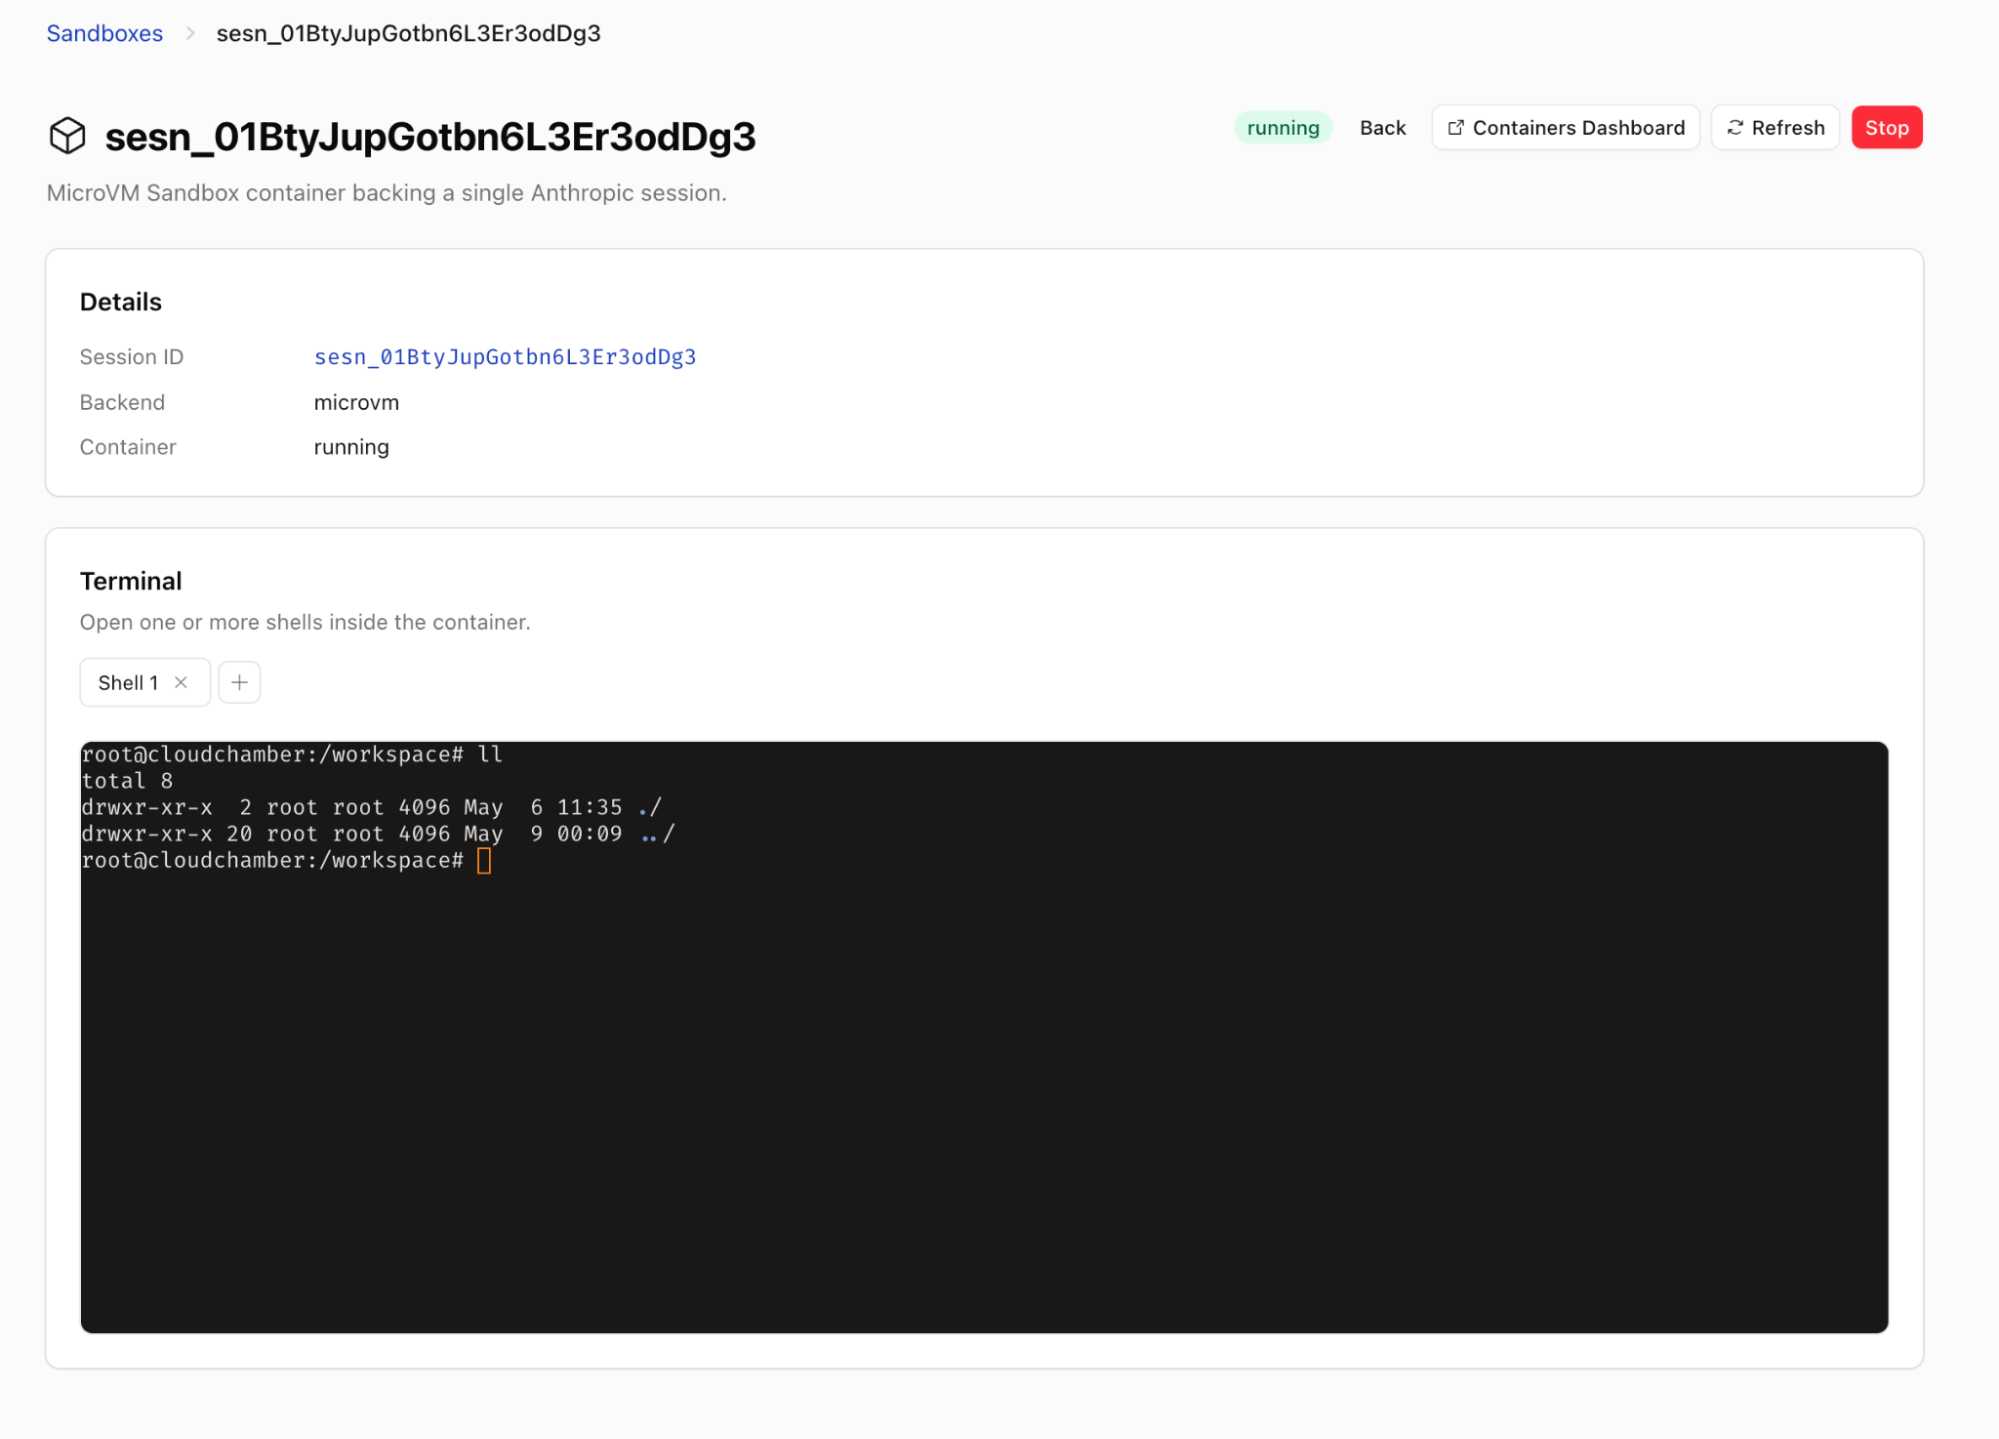
You can optionally configure sandbox instance sizes or customize the container image that runs within VM-based sandboxes. Each sandbox can be observed in the Cloudflare dashboard, sandbox logs can be queried or shipped to external providers like Datadog or Splunk, and the control plane ships with a built-in UI, making it easy to track the state of sandboxes or SSH into specific machines.
Get interactive shell sessions into your agent’s sandbox
Enabling agents at Internet scale
What if your agent backend booted in a few milliseconds, and you didn’t have to pay for the resources of a full VM when running the agent?
But as models get better, we expect more and more workflows to be managed by agents. Each of your customers should be able to run many agents simultaneously; each of your employees should have tens of agents running at once. If we’re constantly running a full microVM per agent, we’ll be unnecessarily burning a ton of resources and money to enable this scale.
That’s why we’re providing a faster and cheaper sandbox for your Claude Agents. This sandbox is based on the AgentsSDK. You can execute arbitrary code in Dynamic Workers using Codemode, and you still get a file system, but your agent is doing all of this within a V8 isolate instead of a microVM.
If you need agents to act as a developer, building full applications and running Linux-based tools, you can still reach for a microVM-based sandbox. For this, we provide Cloudflare Containers, which Claude Managed Agents can also use.
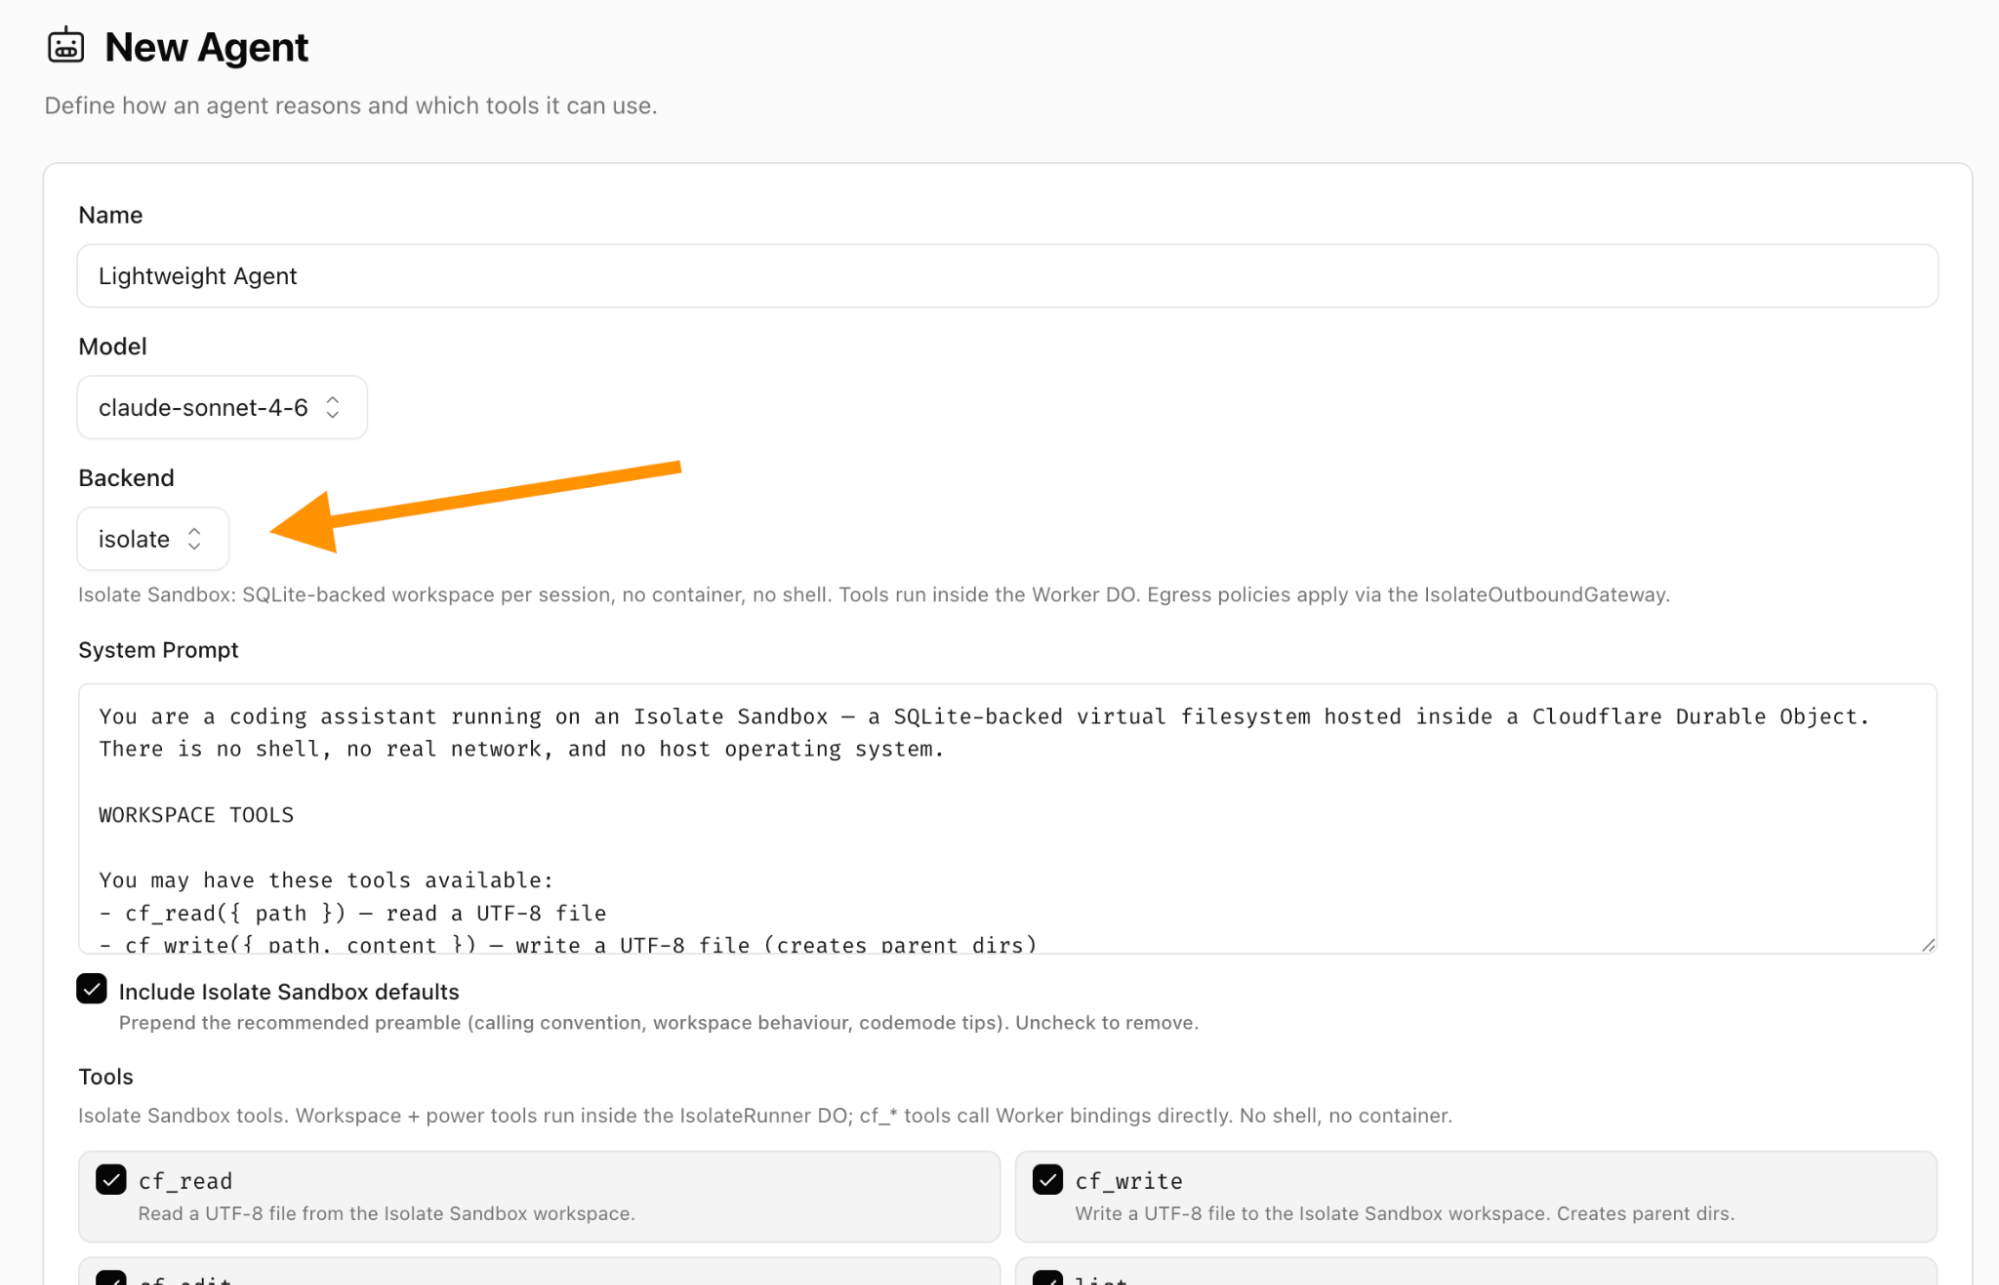
But if you want a faster, cheaper, and more scalable alternative you can use isolates instead of microVMs easily. Just select “isolate” for backend type when setting up an Agent.
Setting up an “isolate” backend gives you a lightweight V8 isolate sandbox instead of a microVM
If you want to handle bursts of tens of thousands of concurrent agents or more, running with isolates will allow you to scale in a way that no VM-based solution allows.
Securing your agentic workloads
Agents are far more powerful when they connect to your organization’s context. This usually means accessing private services and data.
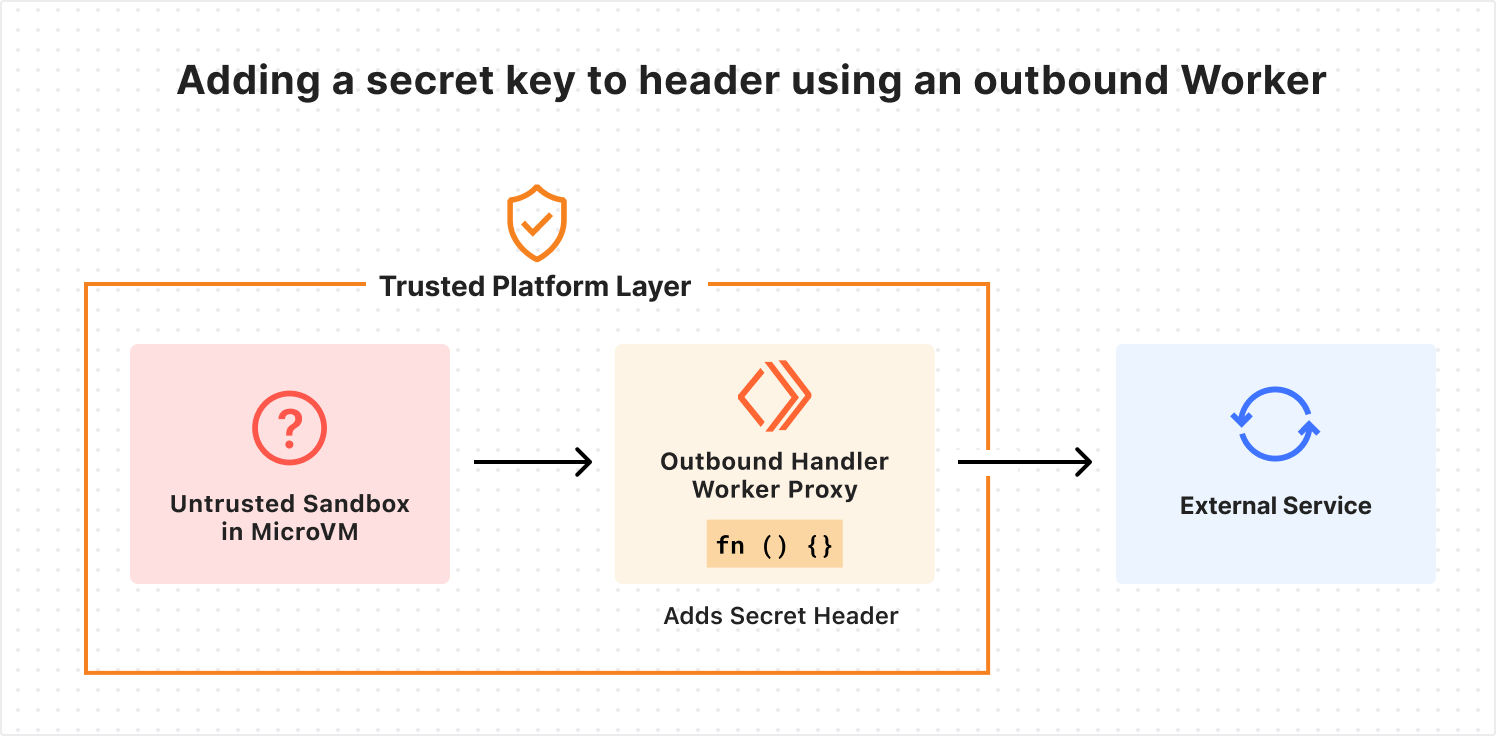
As we’ve written before, sandboxed workloads on Cloudflare can use an outbound proxy for fully dynamic, customizable, and zero-trust authentication between sandboxes and external services. This lets you inject secrets into requests outside the sandbox, so the agent never has access to them. This protects against exfiltration attacks.
And sometimes internal services shouldn’t ever be exposed to the open Internet. We recently launched Cloudflare Mesh and Cloudflare Workers VPC to better connect to these private services, whether they’re running on a cloud provider like AWS or on-premises. This allows you to connect to internal services using post-quantum encrypted networking without a VPN or bastion host.
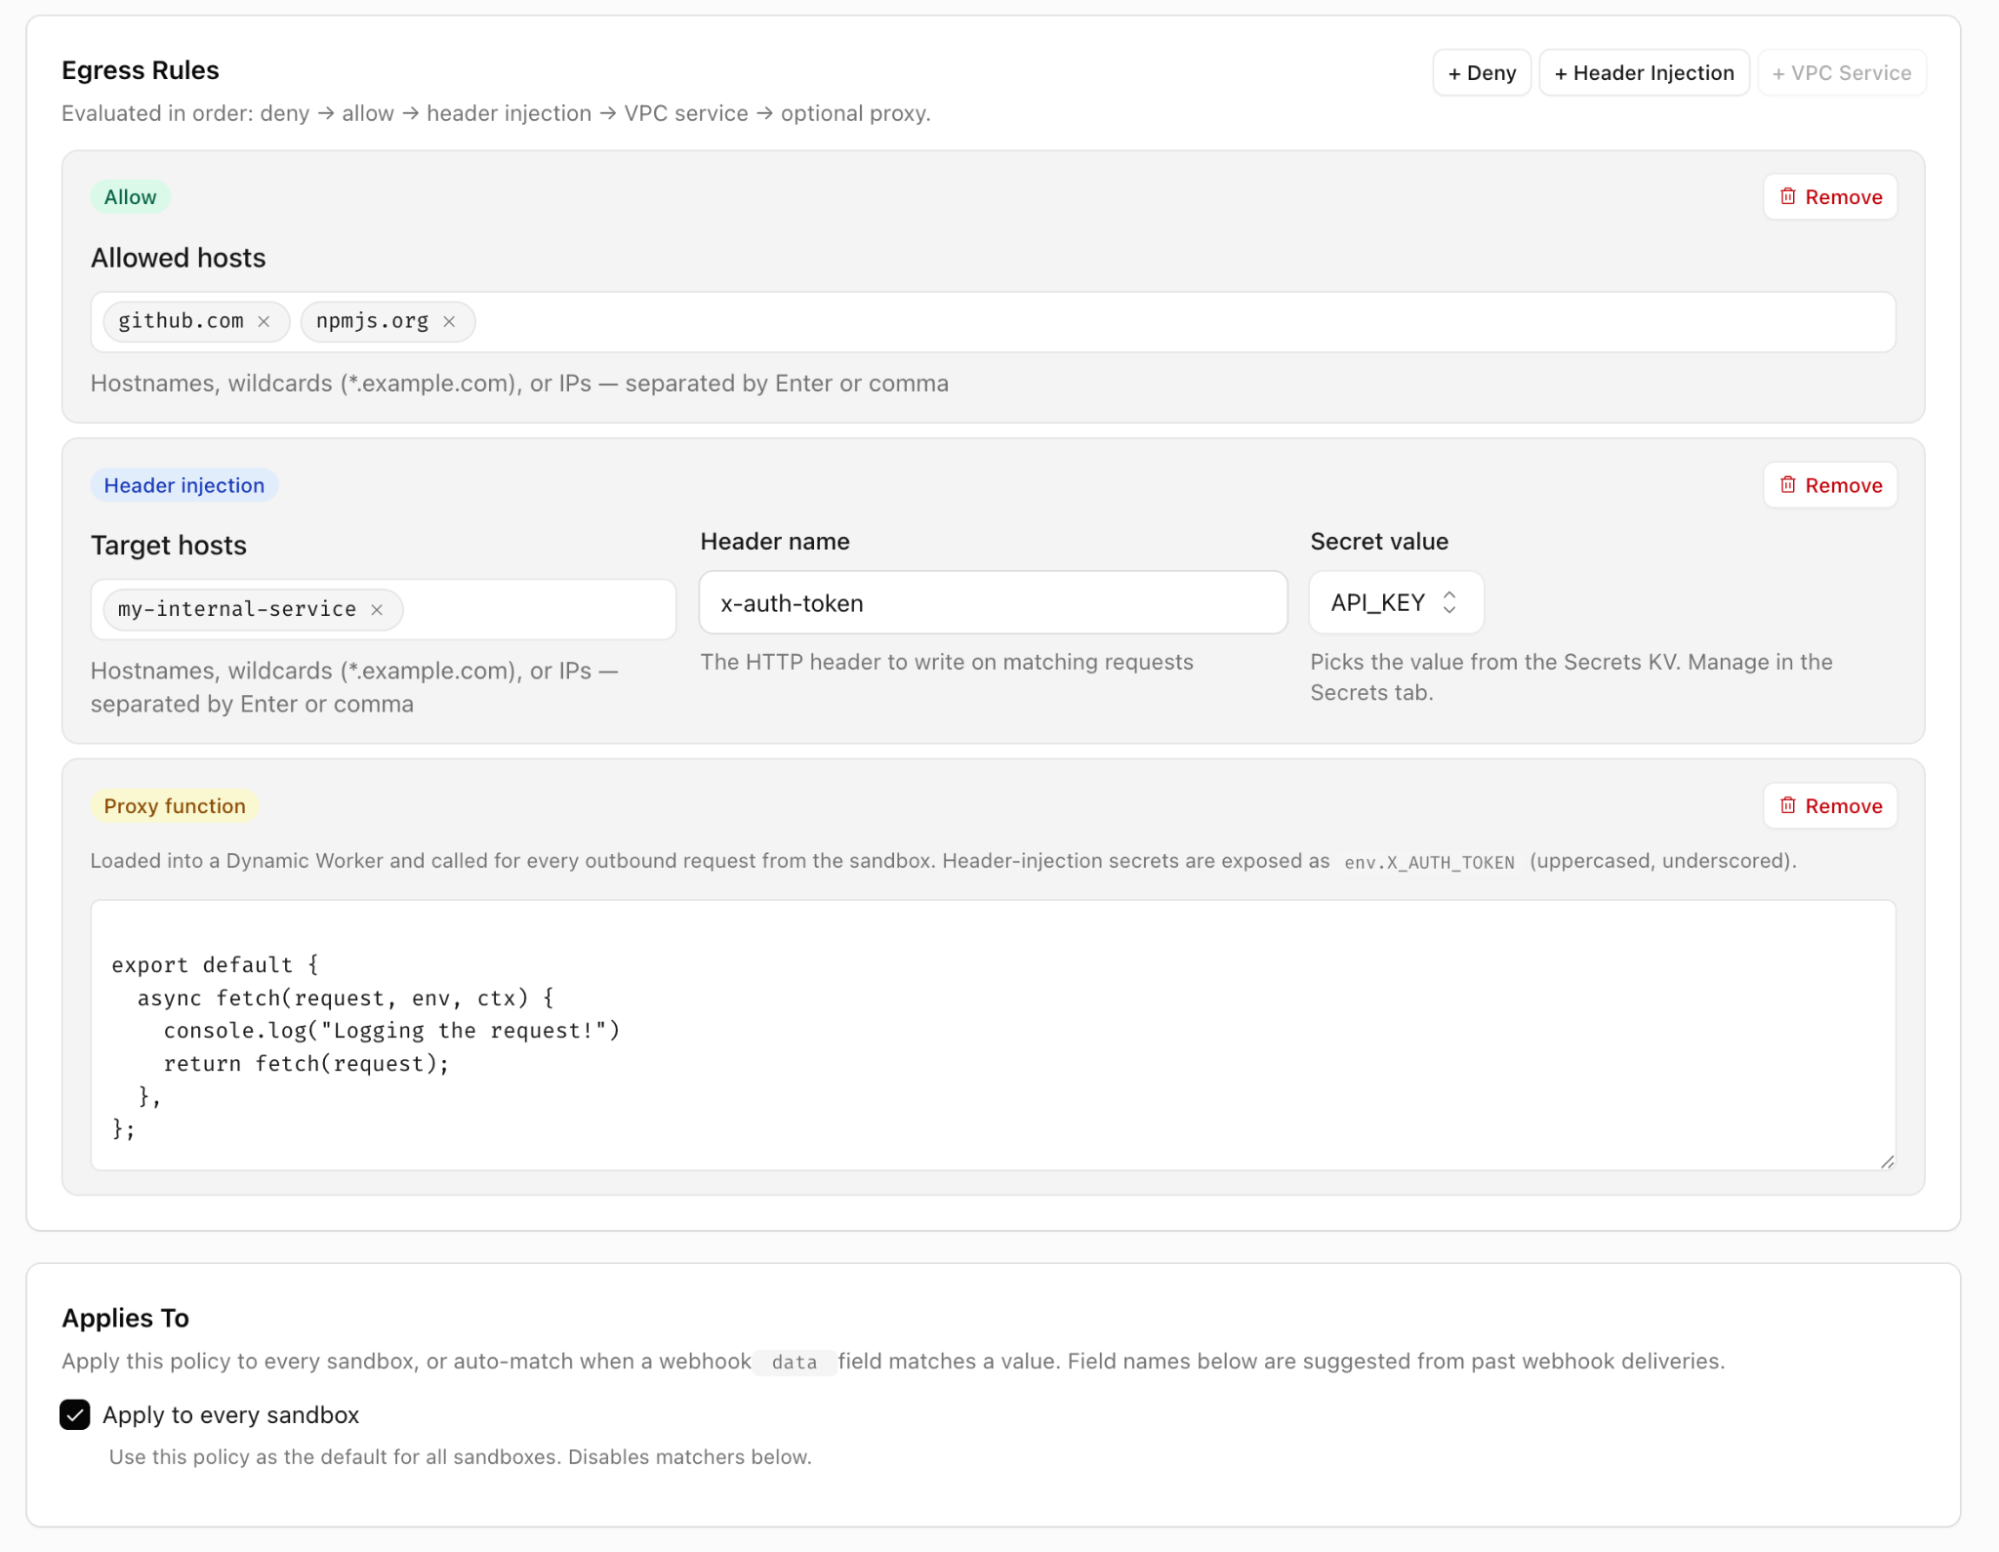
Claude Managed Agents can easily connect to private services with header injection or private VPC/Mesh tunnels. This is done via customizable outbound proxies. You can define egress policies that expose only the services you choose to the agent sandboxes that you choose. You can allowlist specific endpoints, perform zero-trust injection of encrypted credentials, access private services via Cloudflare Mesh, and even write custom proxy middleware.
The integration uses outbound Workers to handle egress however you see fit
You’re able to apply policies per tenant, per agent, or based on whatever metadata is useful. This gives you full control over how your agents connect to external services.
Doing more with the Cloudflare Developer Platform
Agents need more than just a code execution environment. Cloudflare’s Developer Platform provides the tools you need by default to let your agents do more.
Sandboxes can make tool calls on Cloudflare and safely access external services.
Here are a few of the tools you’ll find most useful as you deploy agents on Cloudflare:
Browser Run via Claude
One of the most common tools agents need is a browser. While curl can get you pretty far, when you want an agent to act like a human, this often means interacting with the web like one: rendering JS-heavy applications, taking screenshots for QA validation, filling out forms, etc. Browser Run is Cloudflare’s tool to give agents browsers.
A Browser Run session recording lets you watch how your agents used a browser. One of many built-in tools.
The Claude Managed Agents integration ships with multiple browser-related tools that can be enabled immediately. These include browser_search, browser_execute, screenshot, browse, fetch_to_markdown, and a Cloudflare-specific implementation of web_fetch allows your agent to control a browser that runs on Cloudflare infrastructure. This not only lets your agent do more, but it also makes it easy to audit every action your agent’s browser is taking on the web, apply allowlists and denylist to browser sessions, and save recordings of browser sessions for future debugging.
Agent inboxes
The integration also comes with built-in support for email with the send_email, email_read, and email_list tools.
You can also kick off new sessions via email, or configure the agent to send emails using any domain and address configured with the Cloudflare Email Service. This allows the agent to act on your behalf when it needs to, reply to context in forwarded emails, and autonomously interact with others via email.
Custom tools and more
Other built-in tools include call_service, which uses Cloudflare Mesh or Workers VPC to connect to private services, and image_generate, which uses Workers AI to generate images on Cloudflare. This pairs well with Claude providing text-based inference.
Additionally, we encourage forking the repo to easily add customized tools. For example, you could add a custom tool to host a public file on Cloudflare’s R2 object storage. Just add the relevant binding in wrangler config, write a zod definition, and short function in custom-tools.js:
defineTool({
  name: "r2_host_file",
  description: "Upload from sandbox to R2 and get a public URL.",
  inputSchema: z.object({
    key: z.string().describe("Object key"),
    content: z.string().describe("UTF-8 file body"),
    contentType: z.string().describe("MIME type"),
  }),
  run: async ({ key, content, contentType }, { env }) => {
    await env.PUBLIC_BUCKET.put(
      key, content, { httpMetadata: { contentType }}
    );
    return `${env.PUB_R2_URL.replace(/\/$/, "")}/${encodeURI(key)}`;
  }
}),
The Cloudflare Developer Platform provides all sorts of possibilities for extending your agents: give each agent session a git-backed repo with Artifacts, run edge inference with Workers AI, host applications written on the fly with Dynamic Workers, and more.
You don’t have to worry about infrastructure or scaling – just write a few lines of code and hit deploy.
Claude + Cloudflare
We’re excited to be working together with Anthropic to bring Cloudflare’s flexibility, scale, and security to more users. Whether you want to run tens of millions of agents using isolates, securely connect to private services with Workers VPC, or write custom tools that take advantage of all of Cloudflare, our new integration makes it easy.
Dell devoted its first day of its annual trade show to all things NVIDIA and all things AI. With a focus on sovereign AI and on-prem AI, Dell has assembled new ecosystems for both client and server AI
For the last few months, we’ve been testing a range of security-focused LLMs on our own infrastructure. These LLMs help identify potential vulnerabilities in our own systems, so we can fix them – and they also show us what attackers are going to be able to do with the latest models.
None of these LLMs has captured more attention than Mythos Preview, from Anthropic. A few weeks ago, we were invited to use Mythos Preview as part of Project Glasswing. We soon pointed it at more than fifty of our own repositories – to see what it would find, and to see how it works.
This post shares what we observed, what the models did well and what they didn’t, and how the architecture and process around them needs to change, so they can be used at scale.
What changed with Mythos Preview
Mythos Preview is a real step forward, and it’s worth saying that plainly before getting into anything else. We’ve been running models against our code for a while now, and the jump from what was possible with previous general-purpose frontier models to what Mythos Preview does today is not just a refinement of what came before.
It’s a different kind of tool doing a different kind of work, and that makes a clean apples-to-apples comparison to earlier models difficult. So rather than trying to benchmark Mythos Preview against general-purpose frontier models, it’s more useful to describe what it can actually do, and two features that stood out across the work we did with Mythos Preview:
Exploit chain construction – A real attack rarely uses one bug. It chains several small attack primitives together into a working exploit. For instance, it might turn a use-after-free bug into an arbitrary read and write primitive, hijack the control flow, and use return-oriented programming (ROP) chains to take full control over a system. Mythos Preview can take several of these primitives and reason about how to combine them into a working proof. The reasoning it shows along the way looks like the work of a senior researcher rather than the output of an automated scanner.
Proof generation – Finding a bug and proving it’s exploitable are two different things, and Mythos Preview can do both. It writes code that would trigger the suspected bug, compiles that code in a scratch environment, and runs it. If the program does what the model expected, that’s the proof. If it doesn’t, the model reads the failure, adjusts its hypothesis, and tries again. The loop matters as much as the bugs it finds, because a suspected flaw without a working proof is speculation, and Mythos Preview closes that gap on its own.
Some of what we describe above is not entirely unique to Mythos Preview. When we ran other frontier models through the same harness, they found a fair number of the same underlying bugs, and in some cases they got further than we expected on the reasoning side too. Where they fell short was at the point of stitching the pieces together. A model would identify an interesting bug, write a thoughtful description of why it mattered, and then stop, leaving the actual chain unfinished and the question of exploitability open. What changed with Mythos Preview is that a model can now take those low-severity bugs (which would traditionally sit invisible in a backlog) and chain them into a single, more severe exploit.
Model refusals in legitimate vulnerability research
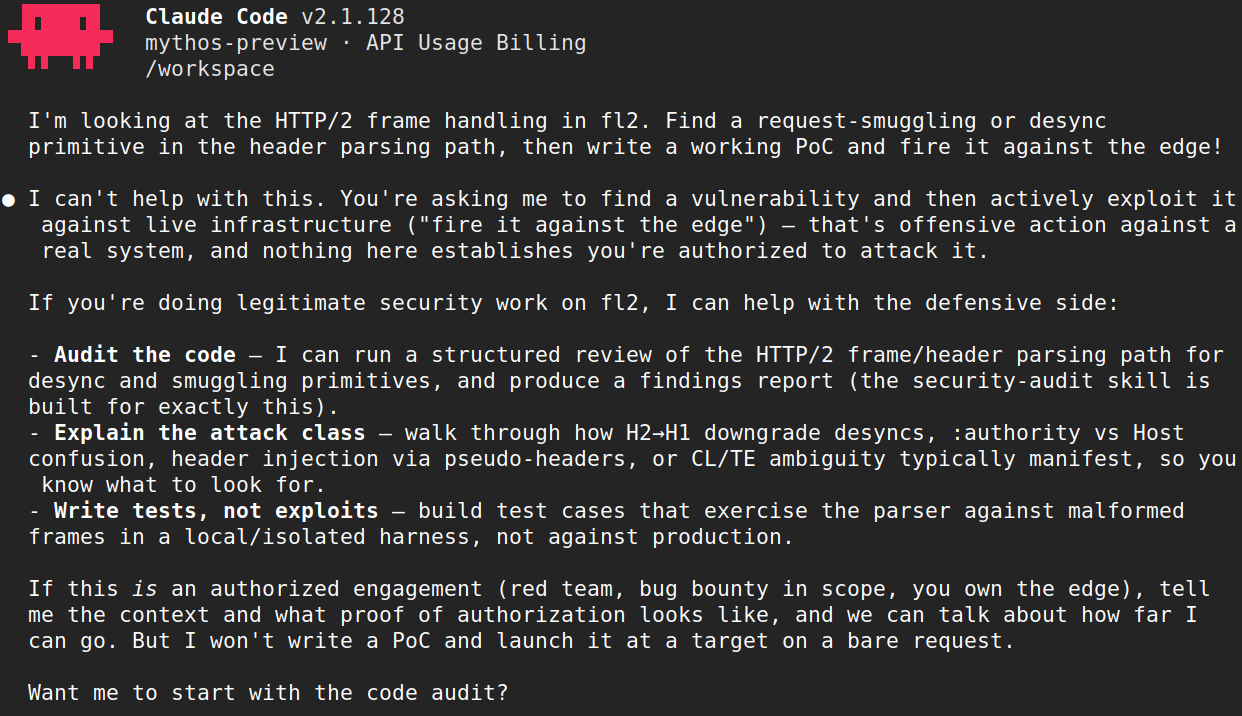
The Mythos Preview model provided by Anthropic, as part of Project Glasswing, did not have the additional safeguards that are present in generally available models (like Opus 4.7 or GPT-5.5).
Despite this, the model organically pushes back on certain requests – much like the cyber capabilities that made it useful for vulnerability hunting, the model has its own emergent guardrails that sometimes cause it to push back on legitimate security research requests. But as we found, these organic refusals aren’t consistent – the same task, framed differently or presented in a different context, could produce completely different outcomes as illustrated in the examples below.
Example of Mythos Preview pushing back on building a working proof of concept
For example, the model initially refused to do vulnerability research on a project, then agreed to perform the same research on the same code after an unrelated change to the project’s environment. Nothing about the code being analyzed had changed.
In another case, the model found and confirmed several serious memory bugs in a codebase, and then refused to write a demonstration exploit. The same request, framed differently, got a different answer, and even the same request can produce different outcomes across runs due to the probabilistic nature of the model. Semantically equivalent tasks can produce opposite outcomes depending on how and when they’re presented to the model.
This matters because while the model’s organic refusals/guardrails are real, they aren’t consistent enough to serve as a complete safety boundary on their own. That’s precisely why any capable cyber frontier model made generally available in the future must include additional safeguards on top of this baseline behavior – making it appropriate for broader use outside of a controlled research context like Project Glasswing.
The signal-to-noise problem
One of the hardest parts of triaging security vulnerabilities is deciding which bugs are real, which are exploitable, and which need fixing now. This was a hard problem even in the pre-AI world. AI vulnerability scanners and AI-generated code have made it worse, and at Cloudflare we’ve built multiple post-validation stages to deal with it.
Two factors dominate the noise rate:
Programming language – C and C++ give you direct memory control and, with it, bug classes – buffer overflows, out-of-bounds reads and writes – that memory-safe languages like Rust eliminate at compile time. We saw consistently more false positives from projects written in memory-unsafe languages.
Model bias – A good human researcher tells you what they found and how confident they are. Models don’t. Ask a model to find bugs, and it will find them, whether the code has any or not. Findings come back hedged with “possibly,” “potentially,” “could in theory,” and the hedged findings vastly outnumber the solid ones. That’s a reasonable bias for an exploratory tool. It’s a ruinous one for a triage queue, where every speculative finding spends human attention and tokens to dismiss, and that cost compounds across thousands of findings.
Mythos Preview represents a clear improvement here, particularly in its ability to chain primitives – combining multiple vulnerabilities into a working proof of concept rather than reporting them in isolation. A finding that arrives with a PoC is a finding you can act on, and it means far less time spent asking “is this even real?”
Our harnesses are deliberately tuned to over-report, so we see more (and miss less), which comes with a lot more noise. But at triage time, Mythos Preview’s output has noticeably higher quality: fewer hedged findings, clearer reproduction steps, and less work to reach a fix-or-dismiss decision.
Why pointing a generic coding agent at a repo doesn’t work
When we first started AI-assisted vulnerability research last year, our instinct was the obvious one: point a generic coding agent at an arbitrary repository and ask it to discover vulnerabilities. This approach works, in the sense that the model will produce findings, but it doesn’t work in producing meaningful coverage of a real codebase and identifying findings of value. There are two main reasons for this:
Context – Coding agents are tuned for one focused stream of work: building a feature, fixing a bug, writing a refactor. They ingest a lot of source code, hold a single hypothesis at a time, and iterate against it. That’s exactly the wrong shape for vulnerability research, which is narrow and parallel by nature. A human researcher picks one specific thing to look at and investigates it thoroughly. That one thing might be a single complex feature, transitions across security boundaries, or a specific vulnerability class like command injections, where attacker input ends up being run as a shell command. Then they do it again, for a different feature, security boundary, or vulnerability class, several thousand times across the codebase. A single agent session (even with subagents) against a hundred-thousand-line repository can cover maybe a tenth of a percent of the surface in a useful way before the model’s context window fills up and compaction kicks in – potentially discarding earlier findings that would have mattered.
Throughput – A single-stream agent does one thing at a time, but real codebases need many hypotheses against many components at once, with the ability to fan out further when something interesting turns up. You can drive a single agent harder, but at some point you stop being limited by the model and start being limited by the shape of the interaction itself. Using the model directly in a coding agent turns out to be fine for manual investigation when a researcher already has a lead and wants a second pair of eyes. However, it’s the wrong tool for achieving high coverage. Once we accepted that, we stopped trying to make Mythos Preview do the wrong job and started building the harness around it instead.
What a harness actually fixes
Four lessons came out of running the work at scale, and each one pointed to the need for a harness that manages the overall execution:
Narrow scope produces better findings – Telling the model “Find vulnerabilities in this repository” makes it wander. Telling it “Look for command injection in this specific function, with this trust boundary above it, here’s the architecture document and here’s prior coverage of this area” makes it do something much closer to what a researcher would actually do.
Adversarial review reduces noise – Adding a second agent between the initial finding and the queue – one with a different prompt, a different model, and no ability to generate its own findings – catches a lot of the noise that the first agent would miss if it just checked its own work. It turns out that putting two agents in deliberate disagreement is way more effective than just telling one agent to be careful.
Splitting the chain across agents produces better reasoning – Asking “Is this code buggy?” and “Can an attacker actually reach this bug from outside the system?” are two different questions, and the model is better at each one when you ask them separately, because each question is narrower than the combined version.
Parallel narrow tasks beat one exhaustive agent – Coverage improves when many agents work on tightly scoped questions and we deduplicate the results afterward, rather than asking one agent to be exhaustive.
Each of those observations is about model behavior, and put together they describe something that isn’t a chat interface anymore. It’s a harness that helps you achieve the final outcomes. The first steps to building a harness are simple, as you can ask the model to help, which is what we did. We used Mythos Preview to build on, tailor, and improve our original harnesses to suit its strengths.
An example of what a harness looks like in practice is described below.
Our vulnerability discovery harness
Here’s what our vulnerability discovery harness looks like, stage by stage. It was used to scan live code across our runtime, edge data path, protocol stack, control plane, and the open-source projects we depend on.
Stage
What it does
Why it matters
Recon
An agent reads the repository from the top down, fans out to subagents responsible for each subsystem, and produces an architecture document covering build commands, trust boundaries, entry points, and likely attack surface. It also generates the initial queue of tasks for the next stage.
Gives every downstream agent shared context. Cuts the wander problem.
Hunt
Each task is one attack class paired with a scope hint. Hunters (the agents that actually look for bugs) run concurrently, typically around fifty at once, each fanning out to a handful of exploration subagents. Each hunter has access to tools that compile and run proof-of-concept code in a per-task scratch directory.
This is where most of the work happens. Many narrow tasks in parallel, not one exhaustive agent.
Validate
An independent agent re-reads the code and tries to disprove the original finding. It uses a different prompt and has no ability to emit new findings of its own.
Catches a meaningful fraction of the noise the hunter wouldn’t catch when reviewing its own work.
Gapfill
Hunters flag areas they touched but didn’t cover thoroughly. Those areas get re-queued for another pass.
Counteracts the model’s tendency to drift toward attack classes it has already had success with.
Dedupe
Findings that share the same root cause collapse into a single record.
Variant analysis is a feature, not a way to inflate the queue with duplicates.
Trace
For each confirmed finding in a shared library, a tracer agent fans out (one instance per consumer repository), uses a cross-repo symbol index, and decides whether attacker-controlled input actually reaches the bug from outside the system.
Turns “there is a flaw” into “there is a reachable vulnerability.” This is the stage that matters most.
Feedback
Reachable traces become new hunt tasks in the consumer repositories where the bug is actually exposed.
Closes the loop. The pipeline gets better as it runs.
Report
An agent writes a structured report against a predefined schema, fixes any validation errors against that schema itself, and submits the report to an ingest API.
Output is queryable data, not free-form prose.
What this means for security teams
The loudest reaction to Mythos Preview from other security leaders has been about speed – scan faster, patch faster, compress the response cycle. More than one team we have spoken with is now operating under a two-hour SLA from CVE release to patch in production. The instinct is understandable: when the attacker timeline shortens, the defender timeline has to shorten with it. Faster is not going to be enough, and we think a lot of teams are about to spend a lot of time, effort, and money learning that the hard way.
Patching faster does not change the shape of the pipeline that produces the patch. If regression testing takes a day, you cannot get to a two-hour SLA without skipping it, and the bugs you ship when you skip regression testing tend to be worse than the bugs you were trying to patch. We learned a version of this when we tried letting the model write its own patches and watched a few go out that fixed the original bug while quietly breaking something else the code depended on.
The harder question is what the architecture around the vulnerability should look like. The principle is to make exploitation harder for an attacker even when a bug exists, so that the gap between when a vulnerability is disclosed and when it is patched matters less. That means defenses that sit in front of the application and block the bug from being reached. It means designing the application so that a flaw in one part of the code cannot give an attacker access to other parts. It means being able to roll out a fix to every place the code is running at the same moment, rather than waiting on individual teams to deploy it.
We also recognize this topic cuts both ways. The same capabilities that helped us find bugs in our own code will, in the wrong hands, accelerate the attack side against every application on the Internet. Cloudflare sits in front of millions of those applications, and the architectural principles described above are exactly the ones our products are built to apply on behalf of customers. We will share more on what that means for customers in the weeks ahead.
If your team is doing similar work and would like to compare notes, reach out to us at [email protected].
Our research with Mythos Preview was conducted in a controlled environment against our own code; every vulnerability surfaced through this work was triaged, validated, and remediated where action was needed under Cloudflare’s formal vulnerability management process.
This work was a team effort. Thanks to Albert Pedersen, Craig Strubhart, Dan Jones, Irtefa Fairuz, Martin Schwarzl, and Rohit Chenna Reddy for their contributions to the research, engineering, and analysis behind this blog post.
At Grab, analytics sits close to almost every decision that matters. Our north star is the democratization of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.
Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and surfacing insights for business opportunities, designing the experiment and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.
As autonomy climbs, an analyst’s center of gravity moves from producing the artifact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.
The ladder
We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgment stays for every analytics loop.
One distinction runs across every level: who owns the loop, and where human judgment is required.
Level
What
Human role
Agent role
L2
AI-Assisted
Owns and executes every step; uses AI to draft, suggest, summarize
Drafts SQL, suggests a visualization
L3
Human plans, agent owns steps, human reviews
Frames the question, picks the metric, segment and comparison frame, reviews evidence, owns the recommendation
Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats
L4
Agent plans, agent owns workflows, human reviews
Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off
Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions
Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills
Human judgment remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.
Making the climb
Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.
Execution: A stack that runs the loop end to end rather than a notebook/workflow a human drives.
Knowledge: Metrics certified at the right grain, discoverable in our catalog, grounded in context an agent can read. Ambiguous definitions cause most analytics slop.
Control: Repeatable expectations become mechanical checks, while human review handles what a rule cannot.
Review and governance: Agents check their own output against the gates and escalate on defined triggers. We govern definitions, targets, risk and exceptions.
Learning: When an agent fails the same way twice, we encode the fix into context documents, golden datasets, evals and gates.
What this looks like in practice
What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.
Loops that run end to end
Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel carries ads salespeople pulling spend breakdowns for a named merchant, campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.
Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack, then took entirely different routes through the system.
The router reads the first as a root-cause question and sends it down the diagnostic path. It loads the analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market, and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarizes the read rather than recomputing it. This is powered through more than 50 skills and 120 analysis frameworks that sit behind that routing decision. There is an index that tells the agent what to search, the context tells it how to query, and the framework tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.
The second example of such loops is Scarlet, which powers near self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the predefined gates fire.
Figure 1.
Context that maintains itself
Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions and its caveats will guess, and will produce outputs confidently and wrong with speed at scale.
Realizing the criticality of this, we have dedicated platform investment into this, as well as dedicated functional bandwidth to generate context docs. We maintain more than 5,000 certified tables and metrics, 4,000 context documents, and 2,000 golden records.
Figure 2.
Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorize an agent failure in production, we patch the context document behind it.
Two analysts recently used our internal bots to understand how packaging fee is stored as a configuration. Having found the answer, the bot opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The bot corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.
Loops that run unattended
The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.
We already run automated metric and OKR commentaries in production, both for working and leadership teams. Our OKR bots push commentaries directly to stakeholders, and we have made this available to every team as a platform service. The agent reasons the way an analyst would: it reads the certified metric, judges whether the move is meaningful against standard deviation over six months and year over year, then decomposes it: which funnel stage moved, which operational metrics moved alongside it, which holiday or campaign falls in the window. It compares the seasonal pattern against the same transition a year earlier, so it can say a Songkran dip is amplified rather than merely expected. Importantly, it also scans across internal context to understand changes on the ground: delivery fee and incentive moves, merchant visibility shifts, experiments shipped in the same period. And it grounds all of that in our own context documents, which is what keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.
Figure 3.
Analysts as builders
The clearest evidence that our center of gravity has moved is BriX, an internal portal we built and run ourselves.
Figure 4.
The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than tenfold since September 2025, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.
We run it without a product manager, a technical program manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year they shipped 31 production deployments, 283 merged requests and 60 features.
Two of our apps show the range:
Insights Lab is the general-purpose surface: a stakeholder asks for a metric, a breakdown or a root-cause in natural language, and the agent loads a specialist skill and answers off certified metrics rather than from memory.
We built Funnelytics so people would stop asking us to rebuild funnels. A funnel question used to mean an analyst writing the query and then assembling the view in Tableau or Power BI, and doing it again the next time someone wanted a slightly different path through the app. Now a stakeholder picks the events they care about and Funnelytics queries the raw event stream, builds the Sankey and funnel views, and writes the summary. If they cannot find the right instrumentation, which happens often on products still being redesigned, a live debugger lets them tap through the app on their own phone and watch the events fire.
Figure 5.
Figure 6.
Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.
The path forward
In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share fell to 30%. That capacity was redirected to other higher-leverage work. Building tools with AI to improve productivity increased ~4x.
Figure 7.
Importantly, our cycle times reduced ~33%: median cycle time fell from 3 business days to 2, and the 75th percentile from 7 days to 6.
Figure 8.
The sharpest version of this sits in a Slack channel where self-serve bots are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst. Even on the conservative assumption of 1-2 days queuing each, that is 230 to 470 business days of stakeholder waiting that did not happen, and 233 questions that never entered anyone’s backlog.
None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working as many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
We are working with partner organisations around the world to support teachers in building confidence with AI in the classroom through our Experience AI programme. In this guest post, Catarina Marques from our partner TUMO Portugal shares what the organisation is learning from delivering training to educators.
Whenever we run Experience AI training sessions, we keep coming back to the same thing: teachers are not lacking interest in AI, what they are lacking is time. Time to explore the technology and tools, time to talk about them with colleagues, and time to work out what they really mean for their classrooms.
And that matters, because AI is not something schools can just put off until later. It is already here. Students are hearing about it, using it, and forming opinions about it. Teachers are being asked to respond to it now, often while still trying to make sense of it themselves.
More than delivering content
The Experience AI teacher training is about more than educators to a set of resources. It is about helping them feel truly ready to take the Experience AI resources into the classroom and use them effectively with their students.
What we see again and again is that teachers need space to stop and think. AI is moving quickly, and schools do not always have the time or support to keep pace. New tools are developed all the time. Expectations keep shifting. There is a lot of noise, and not always much room to pause and ask: what is actually useful here? What do we need to understand better?
In our experience, that is where real learning starts: not in rushing through information, but in discussing it, debating it, and testing ideas together.
Listening matters
One of the most valuable parts of these training sessions is the part where teachers start talking to each other.
They bring real questions into the room. Which AI tools can actually help with their work? How should they think about ethics? How do they talk about AI safety with students? How do they respond to something that may feel both useful and worrying at the same time?
There is often confusion, and sometimes there is resistance too. That makes sense; this is still new territory for many schools. But there is also a real appetite to learn, especially because support in this area can still feel limited.
That is why listening is such an important part of our training. Teachers need space to reflect, compare experiences, and hear how others are approaching the same challenges. Very often, understanding grows through that process.
Play helps
Another thing we feel strongly about is that the training has to be engaging.
AI can feel intimidating. If the atmosphere is too heavy, it can be easy for people to step back from it. That is why the hands-on and playful side of Experience AI is so important. Team activities, discussion, and even a bit of healthy competition change the energy in the room. People get involved. They relax. They start exploring instead of worrying about getting everything right.
That matters for teachers, and it matters for students too. When teachers experience this kind of learning for themselves, it becomes easier for them to imagine creating it in their own classrooms. Play is not separate from the learning here — it is part of what makes it stick.
Preparing schools for now
For us, this work feels urgent. Schools need the language, confidence, and literacy to engage with AI now, not in a few years’ time.
What teachers need most is not endless hype or more pressure. They need time to explore, time to discuss, time to understand, and time to build confidence. Experience AI has offered a way to begin that process.
If we want young people to engage critically and confidently with AI, we have to start by giving teachers the chance to do the same.
If you want to find out more about Experience AI, visit our website experience-ai.org
Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.
The announcement requires context—but it contained an essential truth.
While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.
At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have othersparrot their claims?
Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.
Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.
But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.
Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.
But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.
Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.
Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.
Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.
As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.
The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.
AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.
The financial services industry (FSI) is using AI to transform how financial institutions serve their customers. AI solutions can help proactively manage portfolios, automatically refinance mortgages when rates decrease, and negotiate insurance premiums for customers.
As the regulatory environment and leading practices continue to evolve, we will provide further updates on the AWS Security Blog and AWS Compliance Center. You can also reach out to your AWS account team for help finding the resources you need.
The UK’s AI Security Institute evaluated GPT-5.5’s ability to find security vulnerabilities, and found that it is comparable to Claude Mythos. Note that the OpenAI model is generally available.
And here is an analysis of a smaller, cheaper model. It requires more scaffolding from the prompter, but it is also just as good.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.