As of June 23, 2026, cdnjs, one of the Internet's busiest open-source CDNs, is running exclusively on Cloudflare’s Developer Platform. Along the way, cdnjs surfaced limits in the platform, and the platform grew to meet them.
cdnjs is a free, open-source content delivery network for JavaScript and CSS libraries. Instead of using a bundler or self-hosting jQuery, Bootstrap, or Lodash, you drop a <script> tag pointing to cdnjs.cloudflare.com and the library loads from Cloudflare's edge, instantly, anywhere in the world, with no signup, no API keys, and no rate limits. It's the infrastructure behind a significant portion of “intro to JavaScript” tutorials, CodePen demos, and Stack Overflow answers.
Community-driven, cdnjs is used on roughly 12% of all websites, a 48.3% share of the JavaScript CDN market. It serves an average of 108,000 requests per second, 9 billion per day, across more than 330 Cloudflare data centers, with a 98.6% cache hit rate. Pretty cool, Internet!
In 2011, when bundlers were exotic, npm was barely a year old, and "just drop a <script> tag" was how the web shipped JavaScript, Ryan Kirkman and Thomas Davis built cdnjs as a free, community-run mirror of every popular open-source library.
Cloudflare stepped in to host it free of charge months later, and took over project maintenance in 2019. Back then, Cloudflare didn't have a mature Developer Platform that could fully sustain the entire cdnjs ecosystem. Fifteen years and a lot of building blocks later, the platform is mature enough to run cdnjs end to end, on Workers, Workflows, D1, Queues, Workers Cache, R2, KV, and Containers.
Why cdnjs has 9 billion requests a day
The web has changed beyond recognition from those days. We have ES Modules (ESM), the standardized import / export syntax browsers understand natively. We have import maps, Vite, Bun, Turbopack. We have AI assistants that scaffold entire apps in seconds. Bundlers are everywhere. So why does a CDN for <script> tags still serve 9 billion requests a day?
One reason: LLMs love cdnjs. When ChatGPT, Claude, or Cursor scaffold a quick HTML demo, they reach for cdnjs because their training data is full of it. There have been 15 years of blog posts, GitHub READMEs, tutorial sites, and Q&A threads pointing to cdnjs.cloudflare.com. The URL pattern is consistent and versions are immutable — exactly the kind of dependency a model can produce reliably without hallucinating.
Every file on cdnjs has an SRI hash (we're still working on ensuring all the existing stored hashes match reality due to bugs in the old system), mirrors are auditable, and the whole project is open source. In a world increasingly worried about supply-chain attacks, an immutable, hash-verified mirror of well-known libraries is indispensable.
And it's free, forever, for everyone. No API keys. No rate limits. No "sign up to continue." That's a rare thing on today's Internet, and it's worth protecting.
Why we migrated
We didn't migrate because cdnjs was slow. We migrated because we want to keep improving it.
The previous architecture served users well: 98% cache hit, billions of requests, no outages. But internally, shipping anything new or fixing existing issues in how packages were processed was getting harder. Making a change meant coordinating deployments across GCP Functions, a VM, and Cloudflare. Observability was painful too.
The pain points
In 2020, we migrated cdnjs to serverless, moving file serving onto Cloudflare Workers and KV, with a bare-metal origin as fallback. That change dramatically improved resilience and scalability, and let us pre-compress every asset with Brotli and gzip for smaller, faster responses, but only on the serving side.
The publishing side — the pipeline that watches npm and GitHub for new library versions, downloads them, processes them, and writes the results so cdnjs can serve them — stayed on Google Cloud Platform (GCP). At the time, Cloudflare Workers were designed for fast, short-lived HTTP requests; they didn't yet have the building blocks for a long-running, multi-step pipeline that fetches large tarballs, runs CPU-heavy compression, and orchestrates work over hours. Workflows, Queues, Durable Objects, R2, and Containers didn't exist yet.
So we built the publishing bot on what was available: a chain of GCP Functions, a VM running git-sync, and a GitHub repository as the source of truth. It worked, but six years later, that architecture was showing its age. Here's a diagram of the previous architecture:
The architecture had five pain points. The one that hurt most was observability: debugging meant stitching logs together by hand. We'll start there.
No shared trace A single package update could pass through Cloud Functions, Google Cloud Storage (GCS) object events, Pub/Sub topics, a git-sync VM, and Workers KV before a file reached a user. None of those systems shared a correlation ID. GCP Logging held one half of the story, Cloudflare Logpush held the other, and the two had no common key to join on.
The problem wasn't outright failure, it was partial success. A version that processed cleanly, wrote to KV, and then silently failed to land in the GitHub repo would serve fine for weeks until someone noticed the two stores had diverged. There was no alert for that. There couldn't be, because nothing in the system knew the full pipeline state.
Split-brain storage Files lived in two places at once: Workers KV at the edge (with a bare-metal origin as fallback) and a GitHub repository as the source of truth. The ingestion pipeline wrote to both at the end of every run. Neither was authoritative, and when they drifted, there was no clean way to reconcile them.
Pipeline glued together with object events The ingestion pipeline was a chain of small GCP Cloud Functions, each doing one step and handing off to the next through shared storage. One function fetched the package's release archive from npm and dropped it in a bucket. The bucket firing a "new file" event triggered the next function, which unpacked it and wrote the results somewhere else, triggering the next, and so on. Storage was doing double duty as a message queue, with no dead-letter queue, no backlog visibility, and no clean replay when a step failed.
26 functions for 26 letters Just checking npm for updates required 26 Cloud Functions, one per letter of the alphabet. Each shard had its own deployment and its own logs, and the only way to know if the fleet was healthy was to check all 26.
The GitHub repo GitHub couldn't serve A separate VM ran git-sync, mirroring every processed file into cdnjs/cdnjs. Years of releases pushed it past 1.1TB of packed storage, large enough that GitHub's own archive service refused to generate tarballs or zip downloads for it. Forking became impractical, clones were slow, and the .gitignore had grown to 274 hand-curated entries blocking broken or weirdly-versioned releases. It was a documented graveyard of everything the pipeline couldn't reasonably reject upstream.
A genuine thank you to the GitHub team for hosting this giant for over a decade. They bore with us through years of storage growth, and the project wouldn't have survived without them.
A quieter benefit that came with the migration is having fewer moving parts to secure. Cloud Functions, a git-sync VM, container images, GCS buckets, service-account keys — every one of those was a thing to secure, patch, and audit. Retiring the pipeline closed all of the recently opened cdnjs vulnerabilities.
How we re-built it
The new cdnjs architecture runs entirely on Cloudflare’s Developer Platform.
R2 is the single source of truth for file content. It has no practical size limit, so the files that couldn't fit in KV before, like source maps, big bundles, and font packs, now live alongside everything else. As a bonus, the S3 API makes the entire cdnjs catalog accessible to any S3 client. Maintain a mirror? Open an issue on the cdnjs repository and we'll set you up with read-only credentials.
KV stores only metadata now: package info, version lists, SRI hashes. KV is built for high read volume with infrequent writes, which is exactly the shape of metadata access.
In front of the Worker sits Workers Cache, a tiered cache Cloudflare launched this year. Before, we relied on a separate internal caching layer between the edge and the Worker. That layer is gone now, replaced by one owned by the Developer Platform, the same platform that runs the rest of cdnjs. One less moving part!
The new architecture also extends a long-standing partnership. DigitalOcean has hosted the cdnjs website for years as a sponsor; now it hosts the storage too. Every file published to R2 is mirrored to DigitalOcean Spaces: architecturally a disaster-recovery copy, operationally also a live fallback. The serving worker reads through to it whenever R2 can’t return a file. The chain is cache → R2 → DigitalOcean, so R2 having a bad day doesn't take cdnjs down. A Cloudflare-hosted origin still sits in the chain during the transition, but it will retire once the GitHub backfill lands in R2.
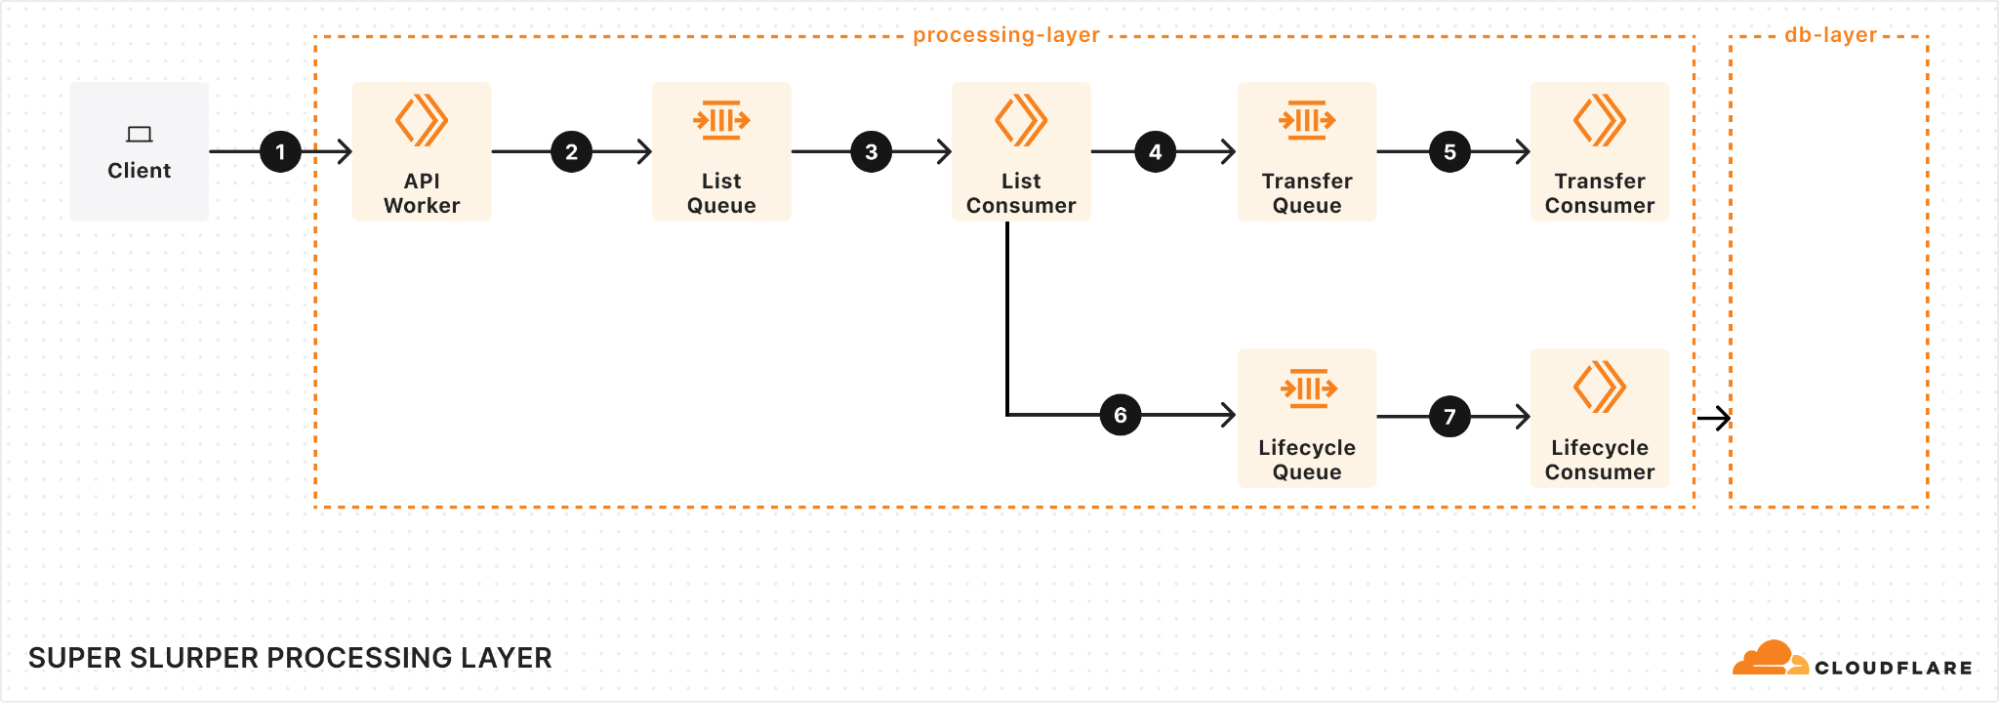
The ingestion pipeline is built on Cloudflare Workflows. Every ten minutes, a cron job triggers PackageUpdatesWorkflow, which checks npm and GitHub for new versions. For each new version found, it spawns a DownloadPackageWorkflow that fetches the tarball into R2, then a ProcessingWorkflow per file that extracts, minifies, and compresses. Finally, PublishingWorkflow writes the results to R2 and KV and updates the Algolia search index.
Because Workflows provides durable execution, the state of each step is preserved. If anything fails — a network timeout, a compression error — the workflow resumes from the last successful step.
The trickier piece is how we glue Workflows to the external compression container. We pre-compress text-based files to streamline the delivery process. But compression is too CPU-intensive for a Worker, so we hand it off to Cloudflare Containers, wait for compression to complete, and then pick up where we left off.
The pipeline has two kinds of waiting:
Per file: Each ProcessingWorkflow writes the uncompressed file to an R2 bucket, sends a job to a Queue, and hibernates. A Rust compression service running in the container picks it up, compresses it, and writes the result to another bucket. An R2 event notification wakes the workflow up so it can continue.
Per package: The parent workflow needs to wait for all its file children before moving on to publish. A package with thousands of files means thousands of children running in parallel. We use a small Durable Object as a counter: a parent increments on each child it spawns, children decrement when they finish. The parent wakes up when the counter reaches zero.
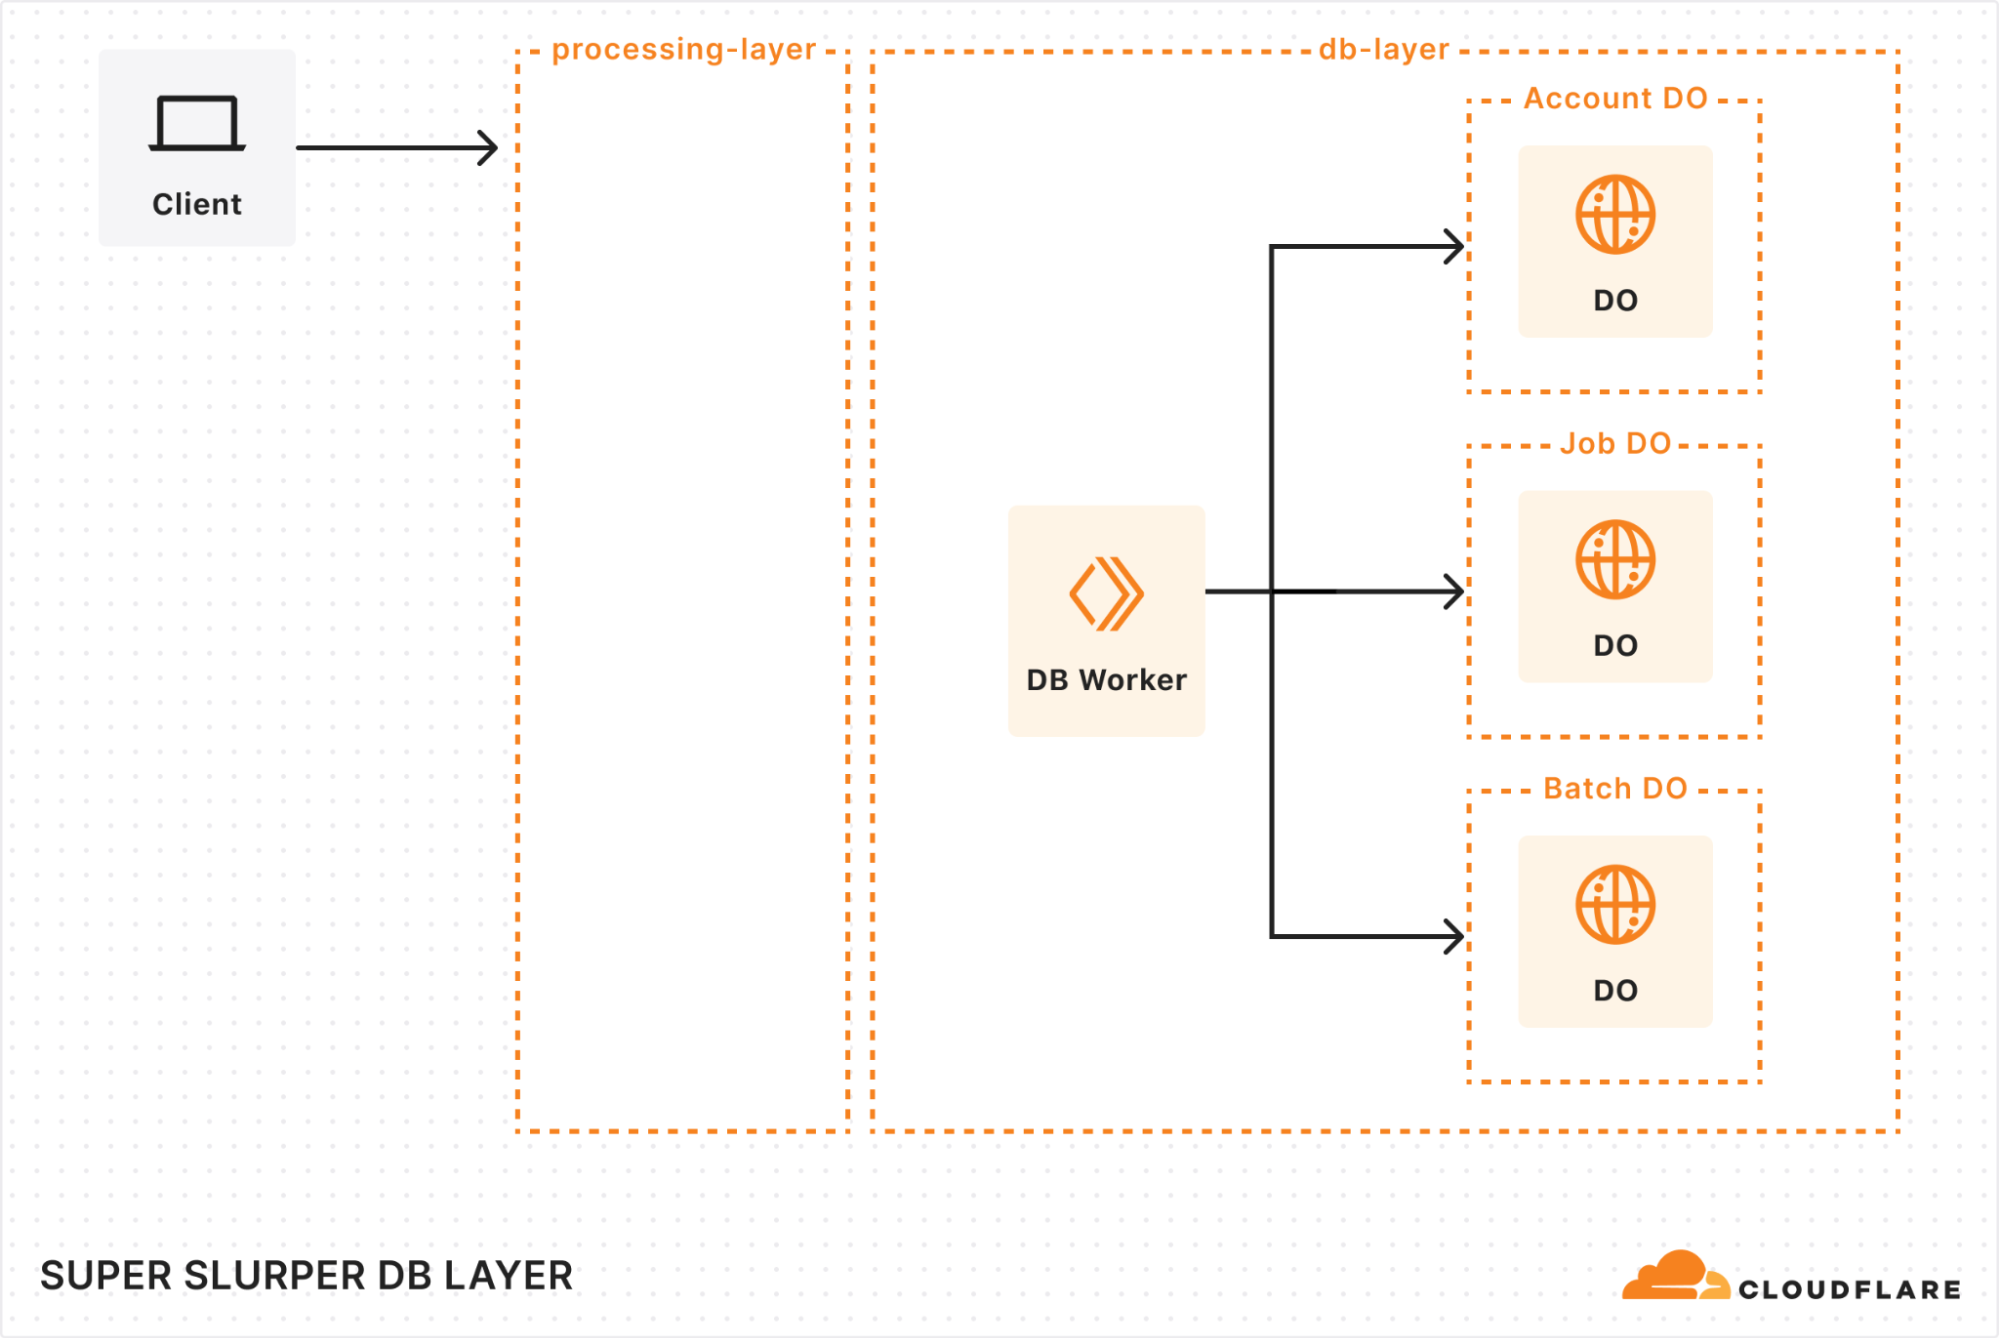
An overview of the new architecture, with R2 as the source of truth and Workflows running the pipeline:
Pushing the limits
Designing the new architecture was one challenge. Migrating the existing catalog into it, without disturbing a single file already in the wild, was another.
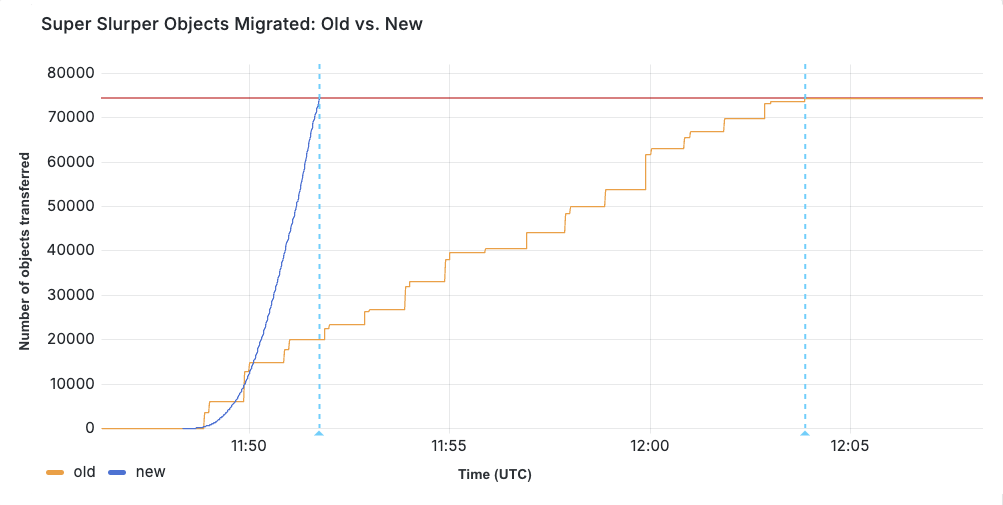
We'd actually tried this once before and had to roll back. The plan, back then, was to re-process old packages and write the results directly to R2, but the regenerated files didn't byte-match what KV had been serving. Minifiers and compressors aren't fully deterministic across versions, so the new outputs were correct but had different SRI hashes. For a CDN where users pin those hashes in their HTML, that's a serving break. So we rolled back, and now, we migrated the existing content from KV to R2 as-is instead of regenerating it.
That decision shifted the problem from "re-process millions of files" to "copy millions of files between accounts, without missing any." And that's where we ran into the Workers subrequest limit, capped at 1,000 per invocation on paid plans. A package with thousands of files would burn through it in one go. Parallelizing didn't help, since every Worker hits the same ceiling. So we sharded the migration by package name and fanned the work out across many invocations via Queues, whose at-least-once delivery guarantee meant no package could silently fall out of the migration.
We hit two platform limits during the migration: 1,000 subrequests per Worker invocation and 1,024 steps per Workflow. Instead of just working around them, we asked the Workers and Workflows teams to raise them — which they did. Subrequests now go up to 10 million on paid plans; Workflows now default to 10,000 steps, configurable to 25,000.
The cdnjs pipeline runs on the same building blocks anyone can use: Workers, Workflows, R2, KV, Queues, Containers, and Durable Objects. The limits we hit are limits we lifted for everyone. If the Cloudflare Developer Platform can serve 9 billion requests a day and publish packages with hundreds of thousands of compressed, minified files, it can probably run whatever you're building.
What’s next
There's an obvious next question hiding in all of this: could cdnjs also serve modern, browser-native ES modules? The same packages, transformed on publish, ready to import without a bundler. The architecture doesn't rule it out. The Workflows-plus-Containers pattern that pre-compresses files today would work just as well for transforming them. We're not committing to it, but it's the kind of thing that's now possible to consider, which wasn't true a year ago.
git commit -m "with love" --author="cdnjs team"
We follow every open issue on GitHub and we want your feedback. Don't hesitate to contribute and help make the Internet better for everyone.
2026 is the year agent harnesses go to production. The software that controls the model’s access to the outside world — harnesses like Codex, Claude Code, OpenCode, Pi, and Project Think — has matured to the point where teams are deploying agents as real, load-bearing infrastructure, not just prototypes.
But building agents that survive production is hard.
We learned this firsthand building Project Think as our first-party agent harness. In working with our customers to run agents in production, we found a common set of distributed systems problems that every agent faces when running in the cloud. When an agent is interrupted, how can it automatically and gracefully resume from where it left off, without losing context or wasting tokens? How can agents run untrusted code securely? How can agents use the tools they were trained for?
A harness can’t solve these problems on its own. They’re tied to state, storage and compute — which means they’re dependent on the platform the agent runs on. That’s why we’re taking our learnings from hardening Project Think for production and bringing them to the Cloudflare Agents SDK as a base layer. Durable execution, dynamic code execution, a durable filesystem and dynamic workflows, now available to any harness building on Agents SDK.
At the same time, a new layer has emerged above the harness. Frameworks like Flue wrap a harness with the project structures, conventions, integrations and developer experience that make agents productive to build.
To solve these scaling challenges, there’s a new, three-layer stack that is emerging for building production-grade AI. Here is how the pieces fit together, moving from the user-facing developer experience down to the underlying platform primitives:
The framework (Flue) — the project structure, the conventions, the integrations, the CLI and the developer experience for building agents.
The harness(Pi, Project Think) — the agentic loop that calls tools, reads results, manages context and keeps going until the task is done.
The runtime/platform(the Cloudflare Agents SDK) — the compute, state, and storage primitives everything above depends on
The Agents SDK is that bottom layer: it makes primitives like durable execution available to any harness and any framework. Flue, our new open-source framework from the team behind Astro, is the first to build on it. Here’s how.
Flue
Flue shipped 1.0 Beta this week, built on the Pi harness, the same harness that OpenClaw is built on. What makes it different as an agent framework is the approach: you don’t script what your agent does, you describe what it knows. Define the context an agent needs — its model, skills, sandbox, and instructions — and it solves whatever task you give it, autonomously. There’s no orchestration loop to write.
This declarative model is what makes writing agents easy: here’s a triage agent that intercepts a bug report, reproduces it in a sandbox, and diagnoses the issue in under 25 lines.
The Flue developer experience
Flue’s power comes from the fact that agents don’t live in isolation. They are built to exist where your users already work, and integrate with your preferred tooling:
Anywhere agents: Drop your agents into Slack, GitHub, Linear, or Discord with pre-configured Channels that handle event verification and dispatch boilerplate automatically.
Headless, but UI-ready: Agents shouldn’t live in a black box. Flue agents can run completely headlessly for background tasks, but @flue/react provides native frontend hooks that stream an agent’s state, tool execution, and live messages straight into your frontend application, without you having to build custom real-time plumbing from scratch.
Ecosystem-ready: Flue makes it easy to add and upgrade integrations with commands like flue add channel slack, generating a Markdown blueprint that your own coding agent can read, modify, and cleanly integrate straight into your codebase.
Designed for production, not just prototypes
Moving an agent out of a local terminal and into a production ecosystem introduces traditional distributed systems failures. Host crashes, API timeouts from LLM providers, and unexpected restarts threaten to erase the short-term memory of a running agent turn.
Flue solves this via Durable Streams. Each event in the execution history is added to an append-only log. By processing every prompt, tool response and model choice as an unchangeable ledger, an agent’s state is never volatile. If a process dies, another simply picks up the log and continues from the exact step it left off.
Deploy anywhere, including Cloudflare
Flue is a multi-cloud framework. On Node.js, each agent runs as a long-lived process. You can deploy it to any VM or container, run it in GitHub Actions, or embed it on an existing server. But when you target Cloudflare, each agent becomes a Durable Object.
By running each Flue agent inside its own Durable Object, Cloudflare can automatically scale to as many agents as you need, each with their own isolated storage and compute. You don’t have to provision servers, manage sticky sessions, or worry about noisy neighbors. And when Flue agents are deployed to Cloudflare, they get durable execution using Agents SDK’s runFiber(), stash(), and onFiberRecovered() methods. Flue also uses @cloudflare/codemode and @cloudflare/shell for sandboxed code execution against a durable workspace.
What harnesses need out of an agentic platform
Flue’s Cloudflare target works so effectively because it maps cleanly to the core primitives we built into the Agents SDK. You can even dig into the Flue source code to understand how Pi, the underlying harness, is adapted to work on Cloudflare Agents SDK.
Here’s how Flue leverages the Agents SDK under the hood, and what it takes to run any modern agent harness reliably at scale.
Every agent harness needs durable execution
An agent turn is not a single request. The model streams tokens, calls tools, waits for results, maybe asks a human for approval, or delegates work to a subagent. That sequence can take seconds or minutes, and at any point the process can be interrupted or crash. When that happens, all of the agent state that was in memory is gone: the streaming connection, the pending tool calls, where the agent was in its turn. Sure, the conversation history is persisted on disk, but the user sees a spinner that never resolves. That’s a broken user experience.
Fibers solve this problem by providing a native checkpointing mechanism directly inside the Agent’s underlying Durable Object. runFiber() records the progress to the Durable Object’s SQLite storage before the work in the Agent turn starts and checkpoints with stash() as the turn advances. When a fresh agent instance boots after an interruption, onFiberRecovered() delivers the last checkpoint, so your agent knows a turn was interrupted, where it got to, and can decide how to continue.
Flue uses runFiber()on its Cloudflare target for exactly this. With the onFiberRecovered() hook, your harness can decide how to resume the execution of the turn, whether it attempts a full reconstruction model like Project Think that repairs turn state or whether it replays certain parts of the turn.
Executing code is better than overloading agents with tools
Agent harnesses give models access to the outside world through tools. But tool surfaces grow fast, and models get worse at selecting the right tool as the list gets longer and the context window fills up with tool definitions. A better pattern: give the model one tool that executes code. The model writes a TypeScript function that calls the APIs it needs, and the harness runs it. We wrote about this when we introduced Code Mode.
The question is where that code runs. To run LLM-generated code securely, you need a sandbox. But typical sandboxes would be slow, cost-prohibitive and inefficient to run each tool call. That’s why the Agents SDK provides @cloudflare/codemode, which wraps Dynamic Workers, to execute LLM-generated code in its own Worker isolate with only the bindings you provide.
Code Mode creates a fresh Dynamic Worker for each snippet, runs it, and discards it. Isolates start in under 10ms and $0.002 per load, resulting in drastically faster and cheaper cost of execution than booting a container every time your agent needs to execute a short piece of code. Flue uses @cloudflare/codemode on its Cloudflare target to power its code tool. The agent writes JavaScript against the workspace and runs it with Code Mode.
You don’t need a full container for most workspace tasks
Agent harnesses often need a filesystem, whether it’s to read files, write outputs, search through code and understand diffs. Coding agents in particular live in the filesystem. But if the harness is running in a serverless environment, how can it get a durable filesystem that persists across executions?
The usual answer is a container. That works, but it’s expensive for what agents mostly do. The majority of filesystem operations in an agent turn are text. Consider a review agent that reads files, greps through source code, or perhaps writes a patch. You don’t need a full Linux boot for that.
@cloudflare/shell gives your agent a durable virtual filesystem inside its Durable Object, backed by SQLite. It provides typed file operations — read, write, edit, search, grep, diff — that agent harnesses can use as tools.
Instead of calling individual tools, a Flue agent running on the Cloudflare target writes JavaScript against the workspace virtual file state API. By running more operations within the Durable Object, the agent benefits from the isolate model’s more efficient execution process, entirely avoiding container overhead:
async () => {
  const files = await state.glob("src/**/*.ts");
  const results = [];
  for (const file of files) {
    const content = await state.readFile(file);
    const todos = content.match(/\/\/ TODO:.*/g);
    if (todos) results.push({ file, todos });
  }
  return results;
}
This translates into a faster and more cost-efficient sandbox environment for agents that need to run shell and filesystem operations to get their work done. And for agents that need a full OS, to run npm install, git, or compilers, Cloudflare Containers provides that. We’re also building @cloudflare/workspace, to keep the virtual file system of a given Durable Object in sync with a container’s, allowing for seamless transition from lightweight Workers to a Linux environment only when it needs one.
Dynamic Workflows: let agents write their own workflows to repeat tasks consistently
But what happens when an agent needs to do more than read files or execute single code snippets? What happens when it needs to orchestrate a massive, multi-step pipeline that must repeat consistently over time, like a code review that successfully resolves bugs or a research workflow that produces good results? A harness can’t provide durable multi-step execution on its own. It needs the platform to persist each step, retry failures, and resume after interruptions.
This pattern is gaining traction. Claude Code recently shipped dynamic workflows, where Claude writes a JavaScript script at runtime to hand off work to dozens of subagents, and the runtime executes it durably. @cloudflare/dynamic-workflows provides this for any harness running on the Agents SDK. Your agent generates a workflow at runtime, and the Workflows engine persists each step, retries failures, and can sleep for hours or wait for external events like human approval.
From the Agent class, runWorkflow() connects your agent to the Workflows engine. The agent kicks off the workflow and can go to sleep. The workflow calls back into the agent via RPC to report progress, update state, or request approval. When the workflow finishes, the agent wakes up with the result.
Direct access to the Cloudflare ecosystem
Beyond compute and storage, agent harnesses need access to external capabilities: web browsing, email, memory, search, inference. A harness shouldn’t have to integrate each of these separately, manage API keys for each, or worry about credentials leaking through agent-generated code.
The Agent class gives your harness access to the rest of Cloudflare through bindings: AI Gateway for per-agent spend tracking and limits, Browser Run for web automation, Email Service for inbox workflows, Agent Memory for persistent recall, AI Search for retrieval, Containers for workloads that need a full OS, and inference across 14+ model providers. Bindings grant capabilities without exposing credentials: your agent uses them, but the keys never enter agent-generated code.
Bring your agents to the agentic cloud
We know this approach works because it is the exact architectural foundation we used to build Project Think, our first-party agent harness. While Project Think remains our highly optimized, out-of-the-box solution for native Cloudflare agent experiences, the Agents SDK ensures that the broader open-source ecosystem can leverage those exact same battle-tested primitives, including Flue.
If you’re building agents today with Flue, you can deploy in just a few clicks to Cloudflare. And if you’re building your own agent harness or you’re building an agent framework, target the Agents SDK and get the platform integration for free.
Cloudflare and Anthropic have collaborated to integrate Claude Managed Agents with Cloudflare Sandboxes. Our new integration gives you more control over your agent sandboxes, secures connections to private services, and improves observability.
In the past year, Cloudflare’s Developer Platform has expanded to give more developers the tools they need to run agents at scale. This includes:
Sandboxes for full stateful Linux microVMs at scale
Agents SDK, providing simple and customizable agent framework
Browser Run, which gives agents fully programmable and observable browsers
Dynamic Workers, allowing for dynamic sandboxed code execution at massive scale
Our goal is to make Cloudflare the simplest, most secure, and most programmable cloud for agents.
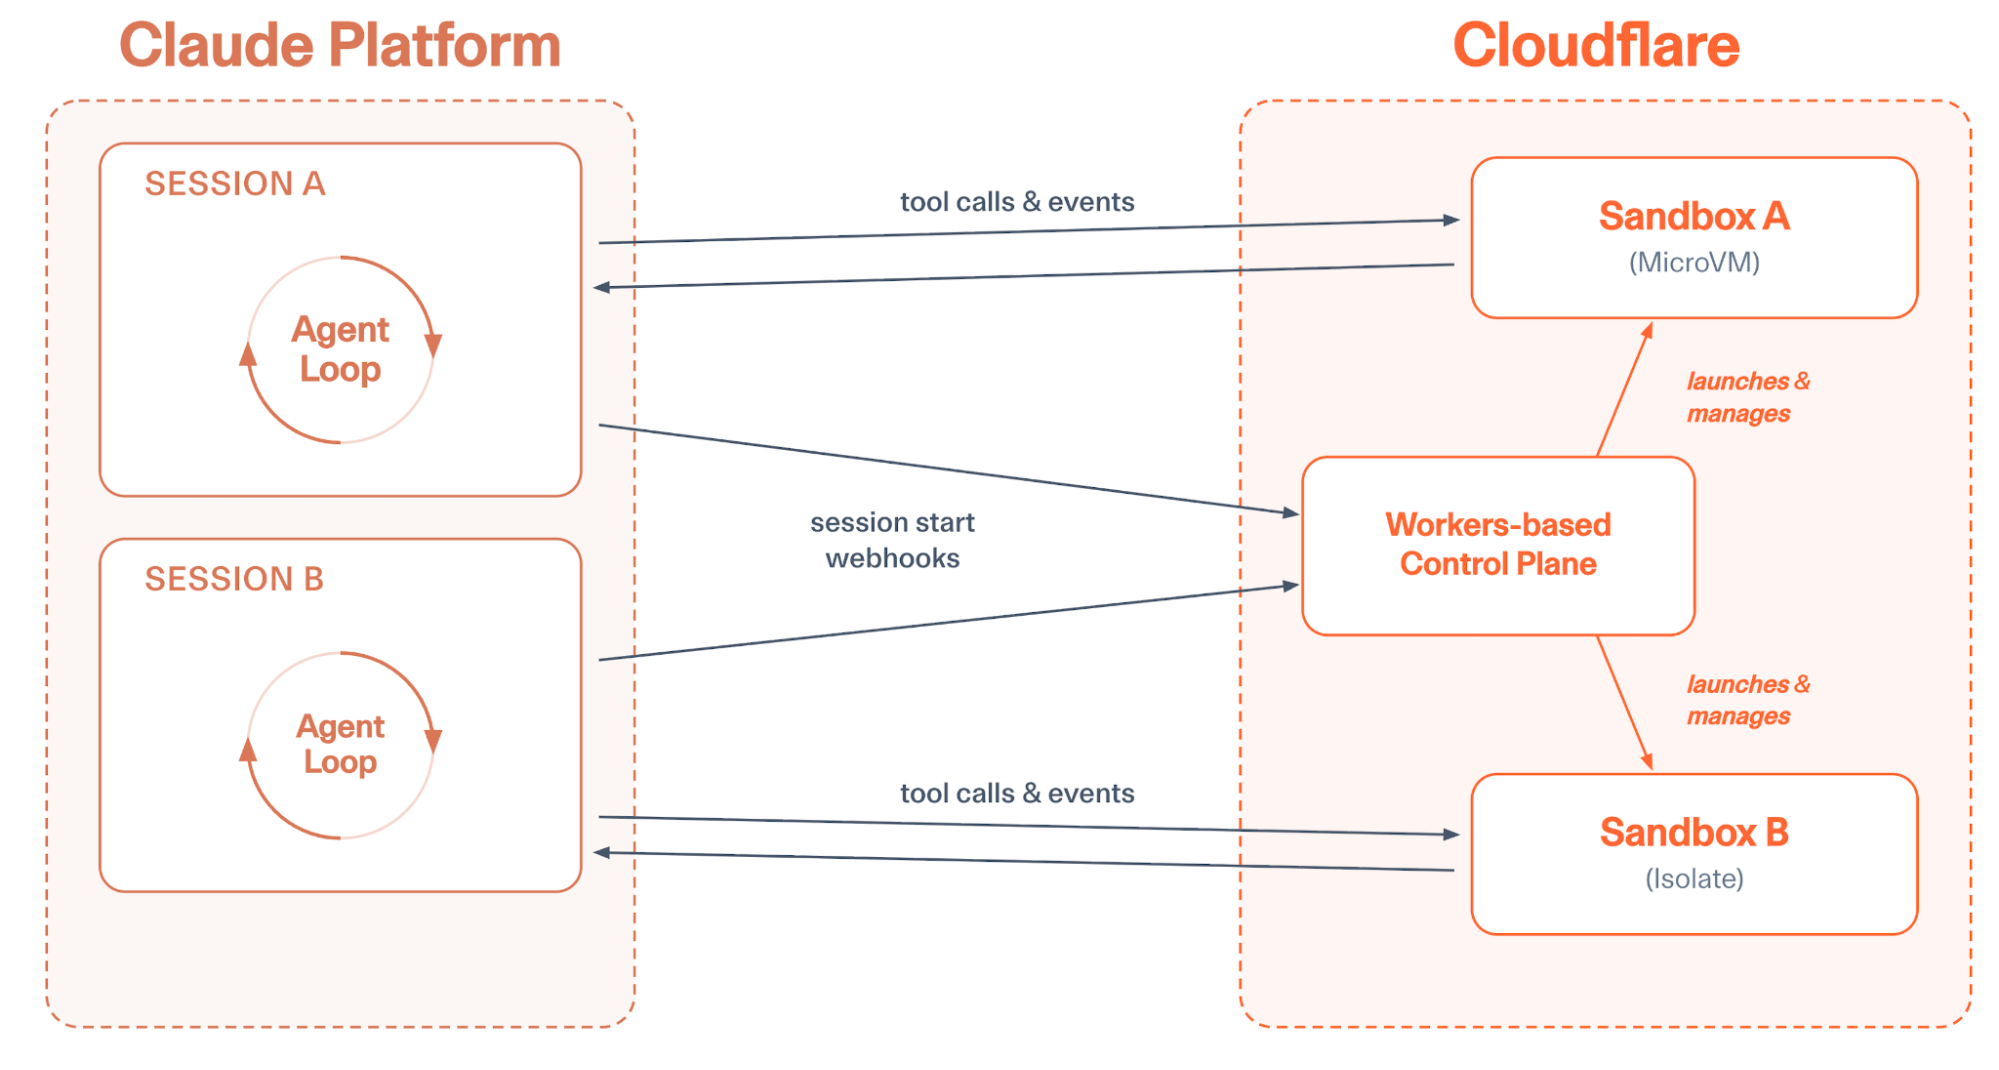
Integrating with Claude Managed Agents is another step in this direction. You can run your agent loop on the Claude Platform, while using Cloudflare to execute code, secure connections, and run custom tool calls.
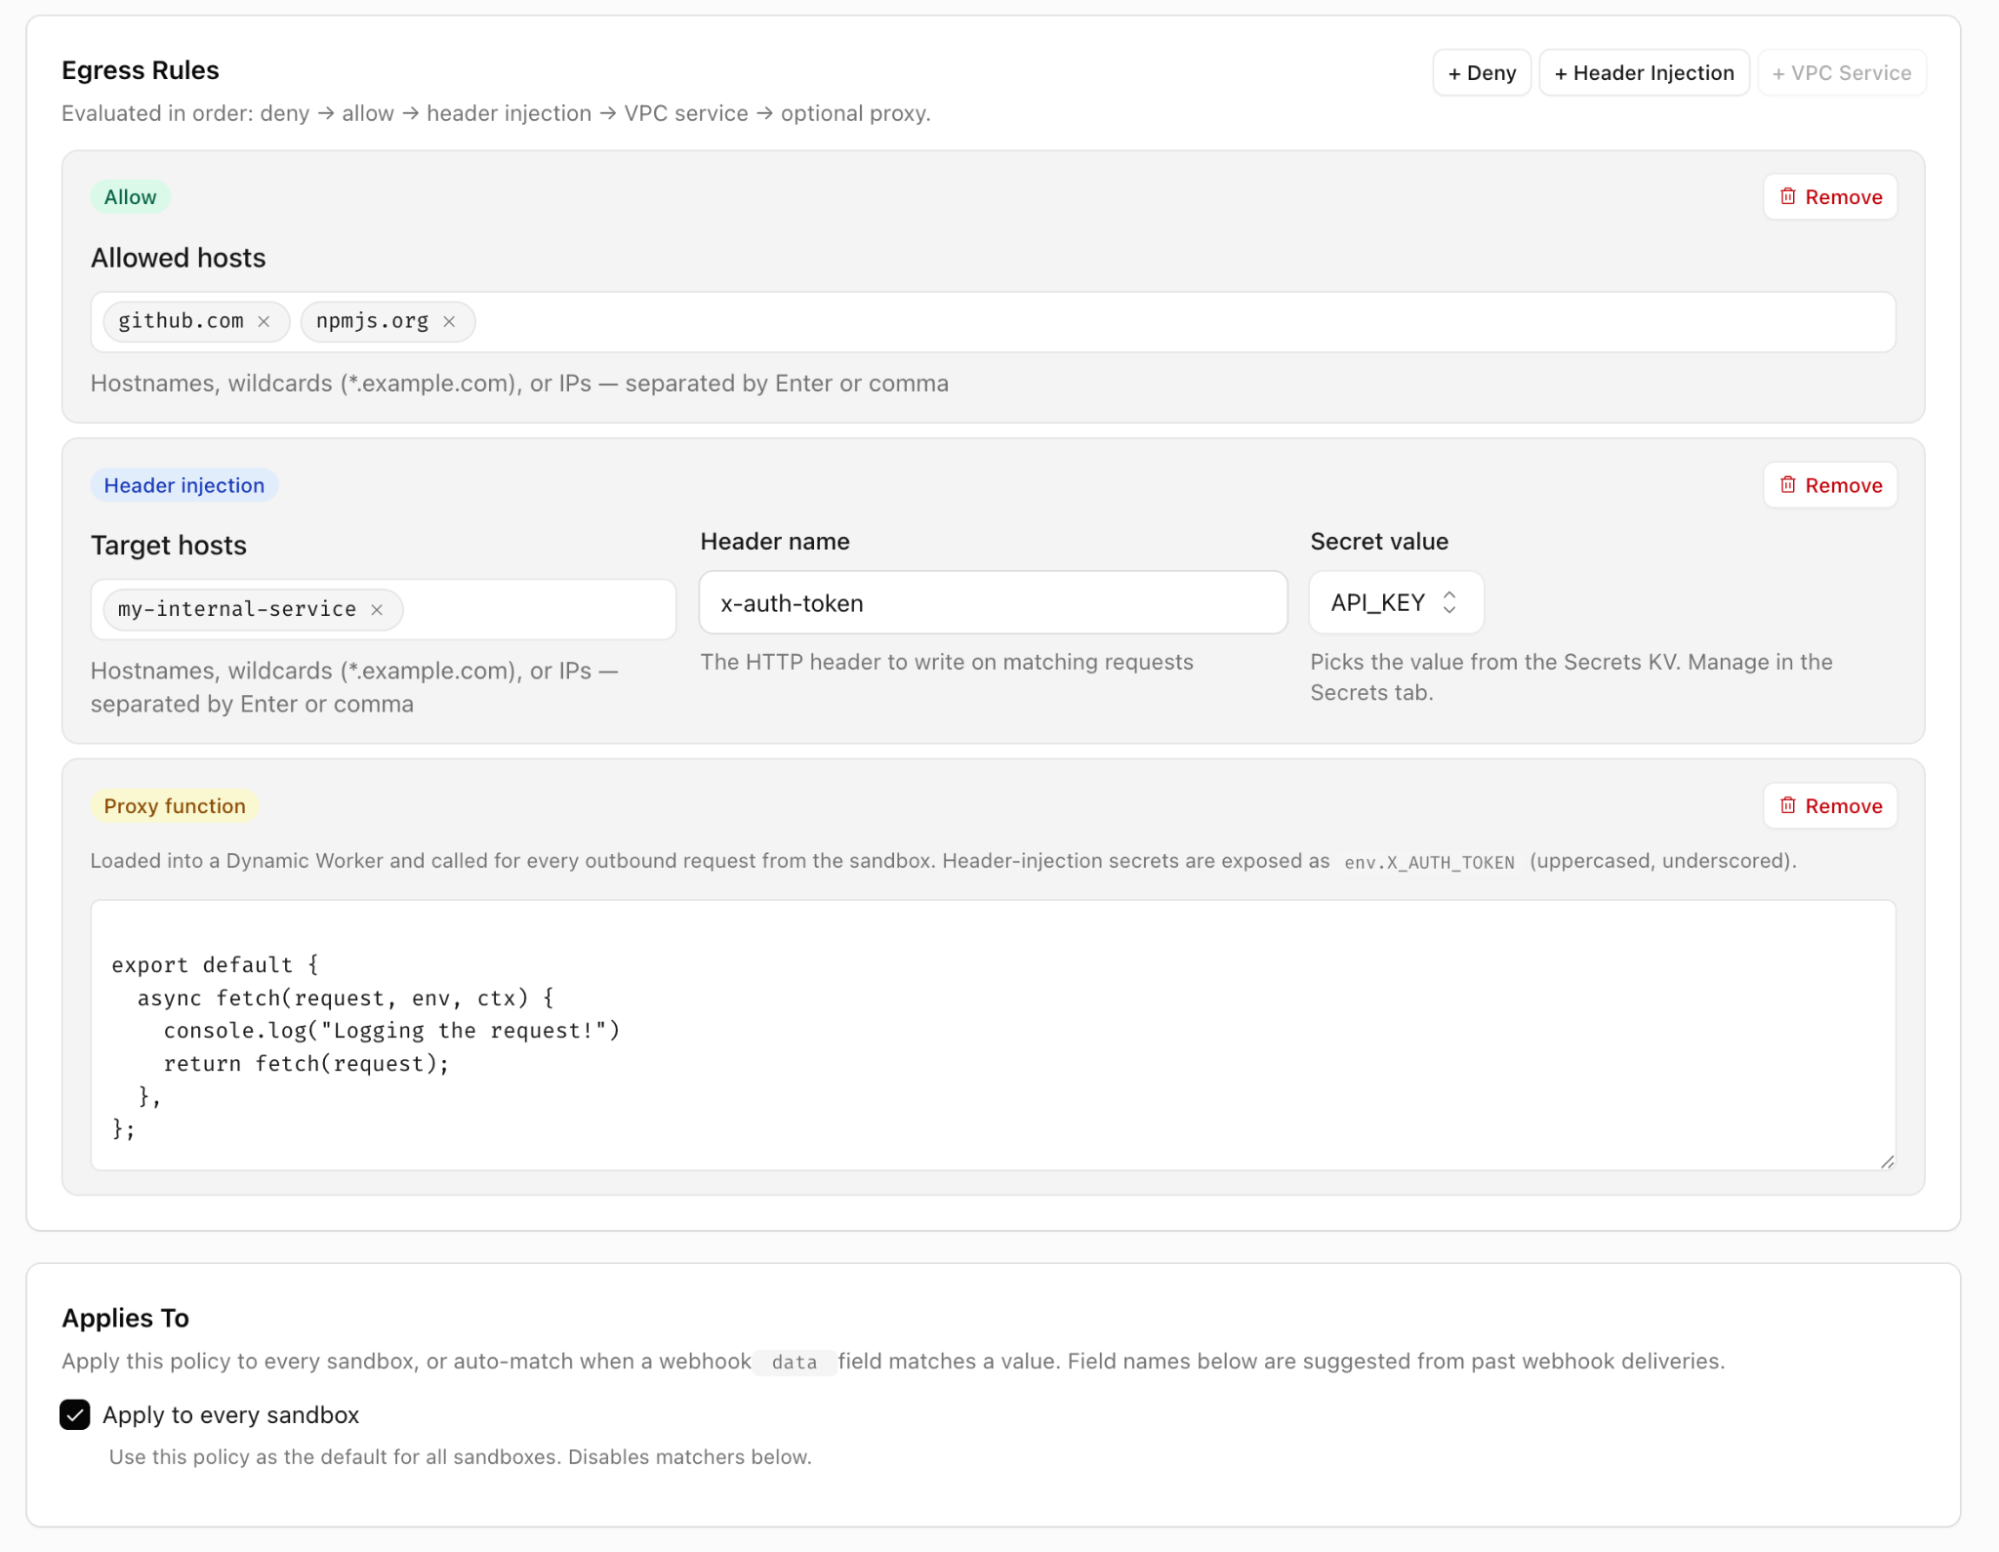
Enhanced security – Run all agent traffic through customizable proxies. This allows you to securely inject credentials, prevent data exfiltration, and better observe how your agents interact with the outside world.
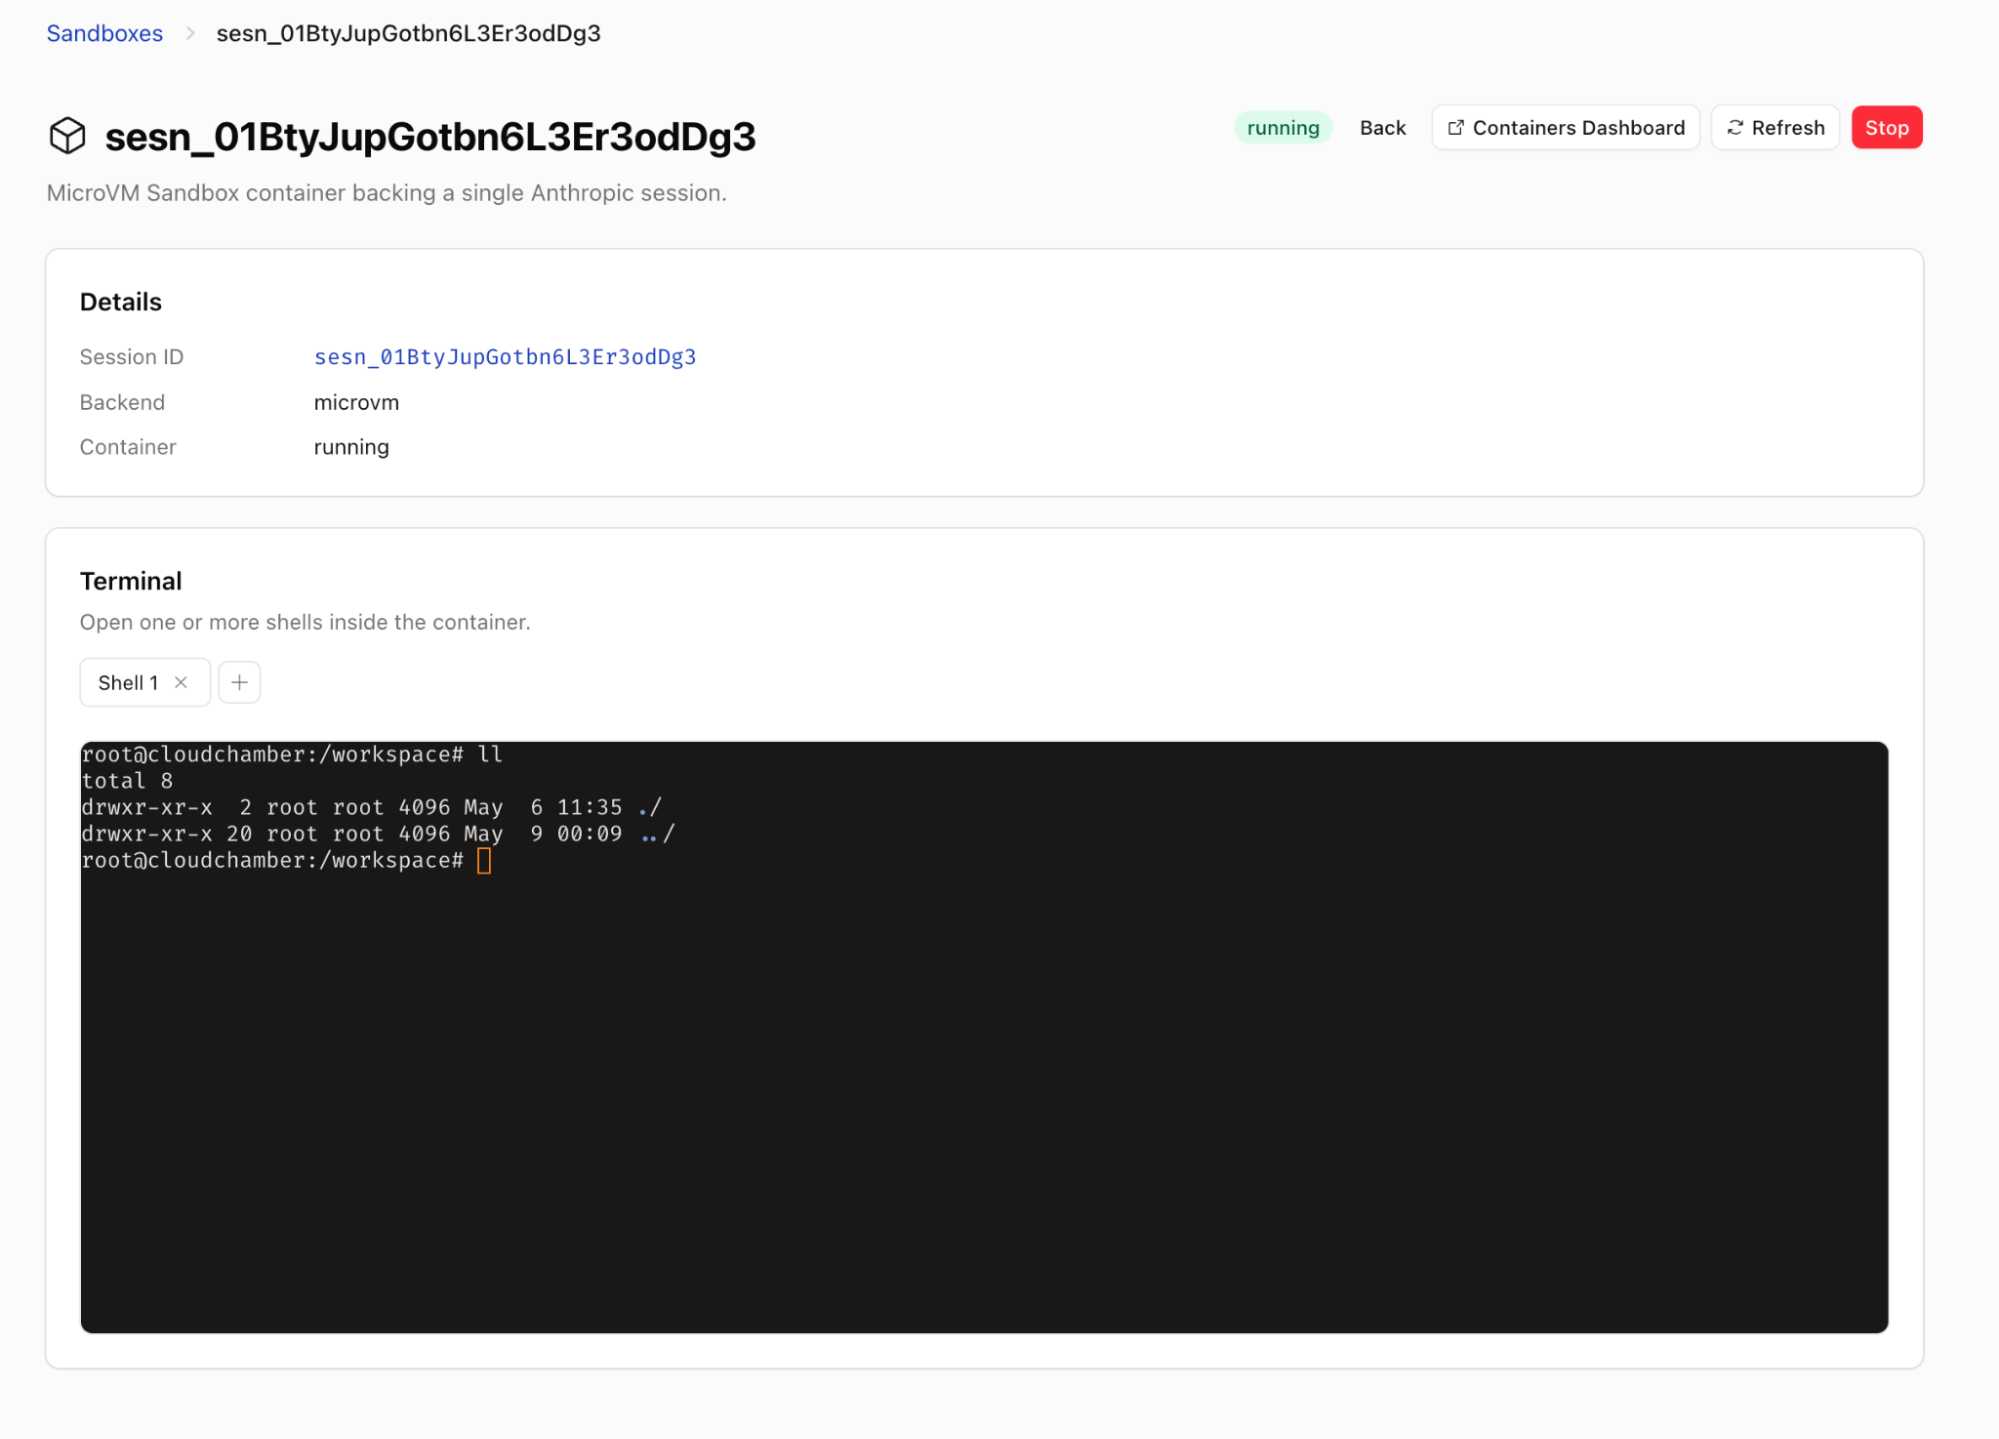
Sandbox control and observability – Get detailed sandbox metrics and logs. SSH into running machines. Customize sandbox images.
Lightweight sandboxes – Writing and executing untrusted code can be done in a traditional microVM or a lightweight isolate. This lets you hit massive scale, boot sandboxes in milliseconds, and minimize infrastructure spend.
Private service connectivity – Connect agents to private internal services without ever exposing them to the Internet.
Browser Control and Observability – Get an audit trail of every agent’s browser sessions, including session recording and human-in-the-loop flows.
Email – Give each of your agents its own email address and ability to send emails.
Custom tools – Extend your agents with tools without needing additional infrastructure. Just write functions and deploy.
You get all of this out of the box when deploying the integration, and you can easily customize if you need more.
Let’s take a brief look at Claude Managed Agents, see how to integrate a Cloudflare-based environment, then explore how to get the most out of Claude on Cloudflare.
An overview of Claude Managed Agents
Claude Managed Agents allow developers to easily define and run agents on the Anthropic platform. In these managed environments, Claude can read files, run commands, browse the web, and execute code. The harness supports built-in prompt caching, compaction, and various agent-first performance optimizations.
Until now, using Claude Managed Agents has meant running the entire stack on Anthropic-provided infrastructure. While this is great for some developers, others may need more control over their infrastructure choice, whether this is for security, compliance, or performance reasons. Self-managed environments for Claude Agents provide just that.
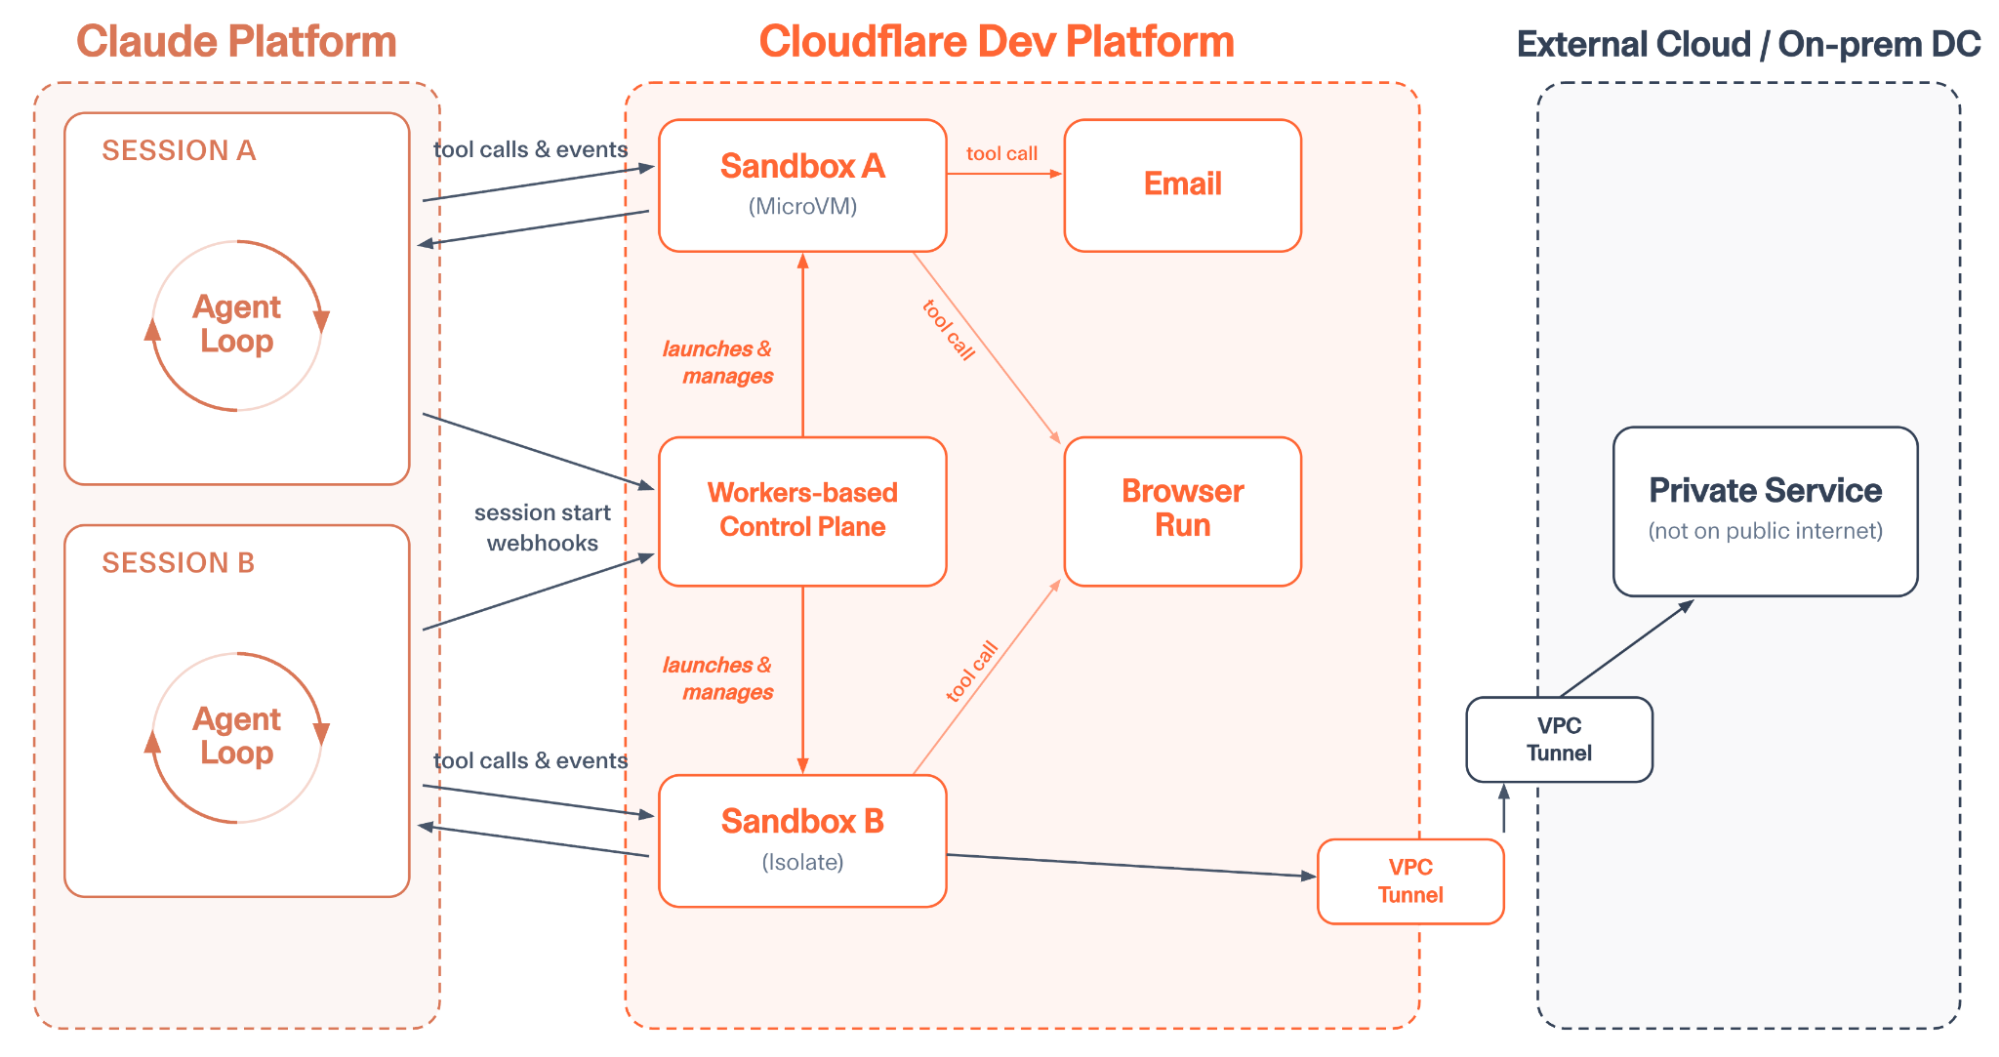
Anthropic describes this as “decoupling the brain from the hands.” The core agent loop runs in Anthropic (the “brain”), but the infrastructure for running and executing code (the “hands”) can be run anywhere, including Cloudflare.
The Cloudflare environment
Our new integration gives your agents a Cloudflare-based environment for running and executing code within minutes.
Follow the onboarding guide to get started. Then fork the repo and customize your integration as you see fit.
After setup, when a Claude Agent starts a session, it sends a message to your new Cloudflare-based control plane. The Workers-based control plane gives each agent session a sandboxed environment for executing code, developing applications, running CLI tools, and more. State is automatically persisted across session sleeps.
Sandboxes write files and execute code in response to the Claude-based Agent loop
You can optionally configure sandbox instance sizes or customize the container image that runs within VM-based sandboxes. Each sandbox can be observed in the Cloudflare dashboard, sandbox logs can be queried or shipped to external providers like Datadog or Splunk, and the control plane ships with a built-in UI, making it easy to track the state of sandboxes or SSH into specific machines.
Get interactive shell sessions into your agent’s sandbox
Enabling agents at Internet scale
What if your agent backend booted in a few milliseconds, and you didn’t have to pay for the resources of a full VM when running the agent?
But as models get better, we expect more and more workflows to be managed by agents. Each of your customers should be able to run many agents simultaneously; each of your employees should have tens of agents running at once. If we’re constantly running a full microVM per agent, we’ll be unnecessarily burning a ton of resources and money to enable this scale.
That’s why we’re providing a faster and cheaper sandbox for your Claude Agents. This sandbox is based on the AgentsSDK. You can execute arbitrary code in Dynamic Workers using Codemode, and you still get a file system, but your agent is doing all of this within a V8 isolate instead of a microVM.
If you need agents to act as a developer, building full applications and running Linux-based tools, you can still reach for a microVM-based sandbox. For this, we provide Cloudflare Containers, which Claude Managed Agents can also use.
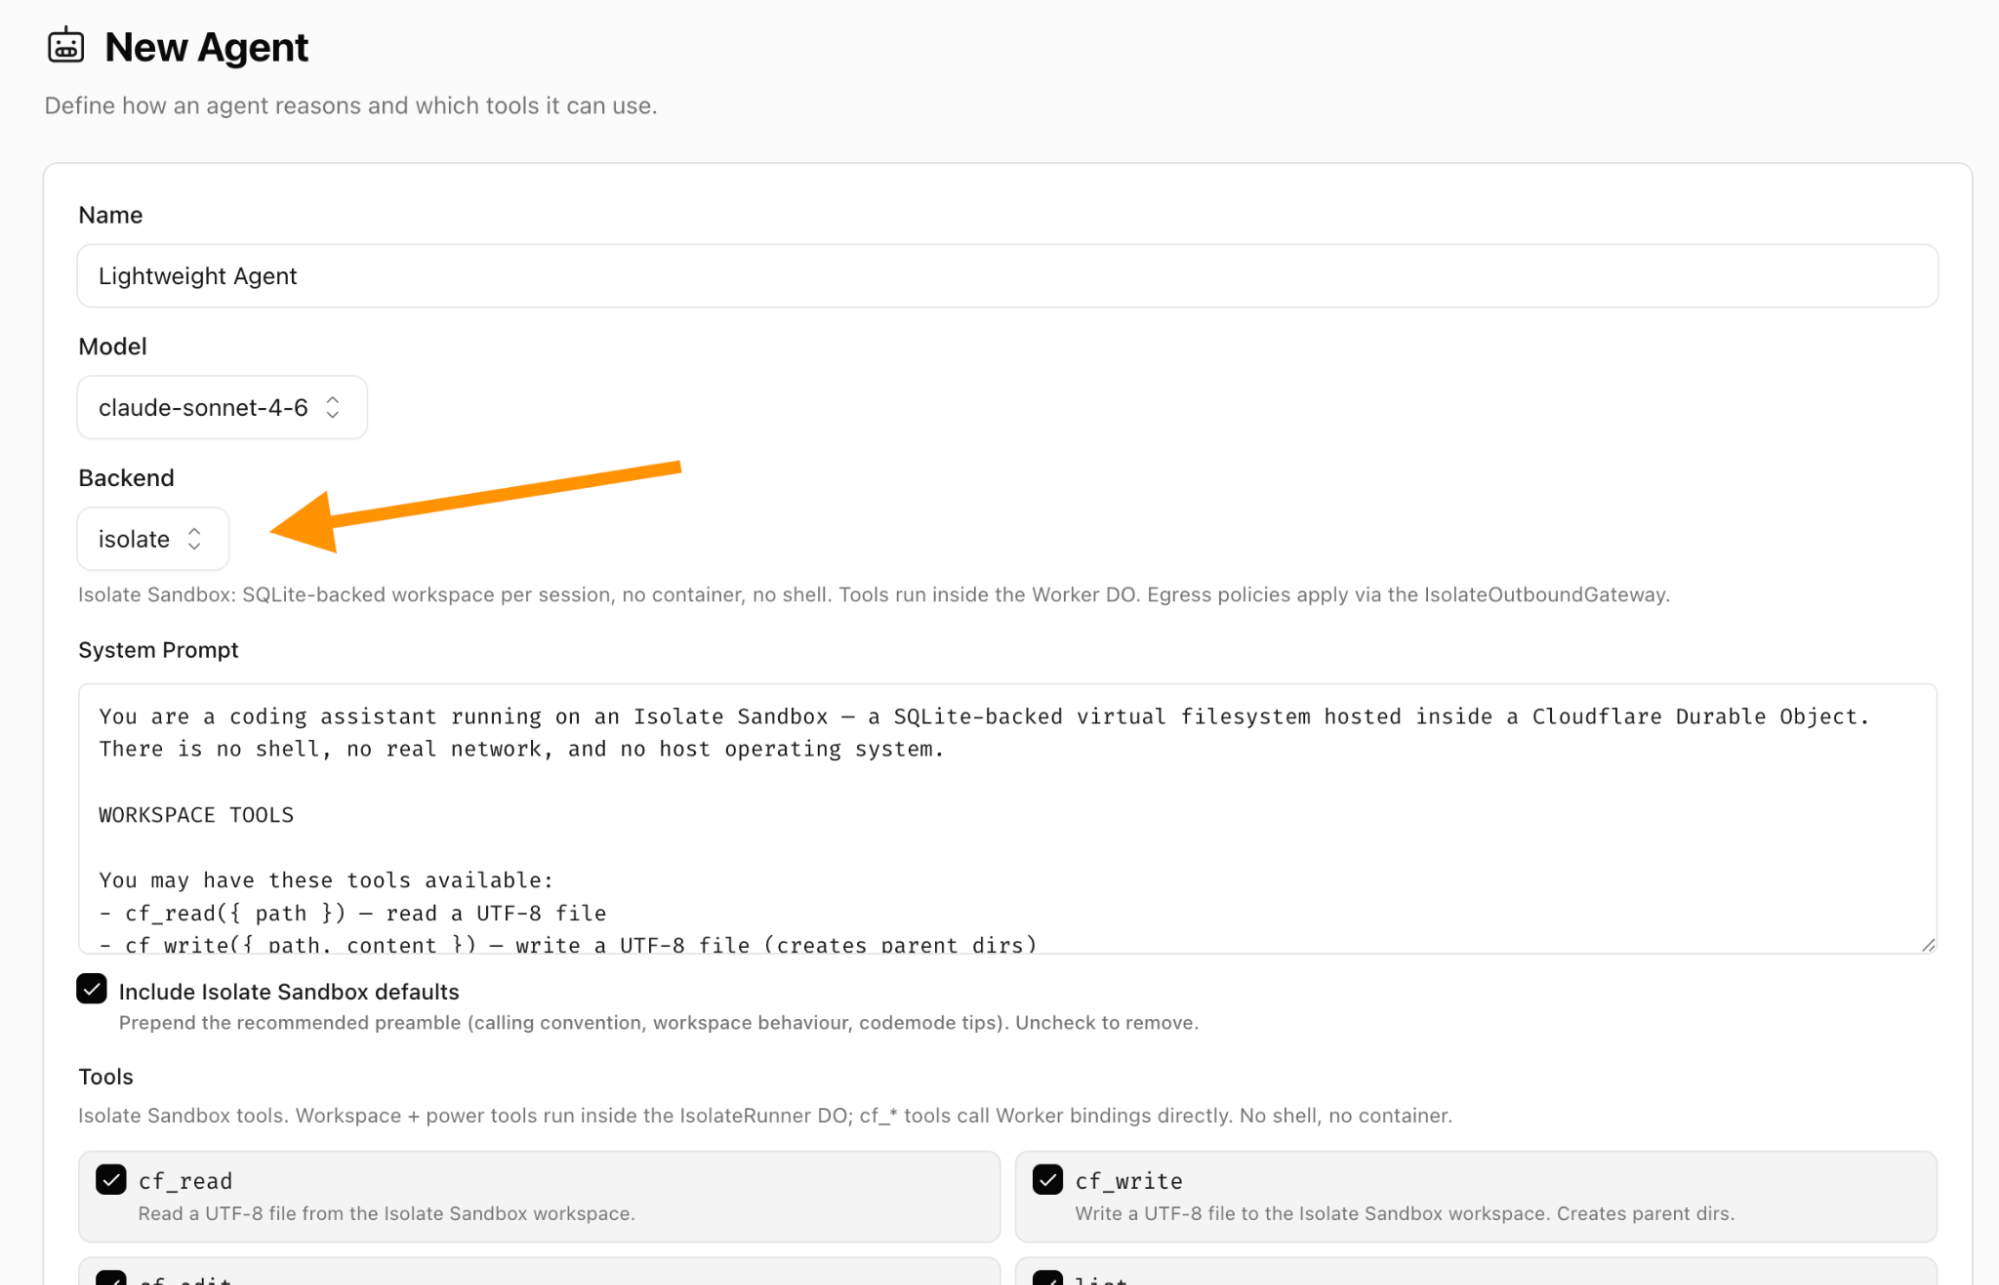
But if you want a faster, cheaper, and more scalable alternative you can use isolates instead of microVMs easily. Just select “isolate” for backend type when setting up an Agent.
Setting up an “isolate” backend gives you a lightweight V8 isolate sandbox instead of a microVM
If you want to handle bursts of tens of thousands of concurrent agents or more, running with isolates will allow you to scale in a way that no VM-based solution allows.
Securing your agentic workloads
Agents are far more powerful when they connect to your organization’s context. This usually means accessing private services and data.
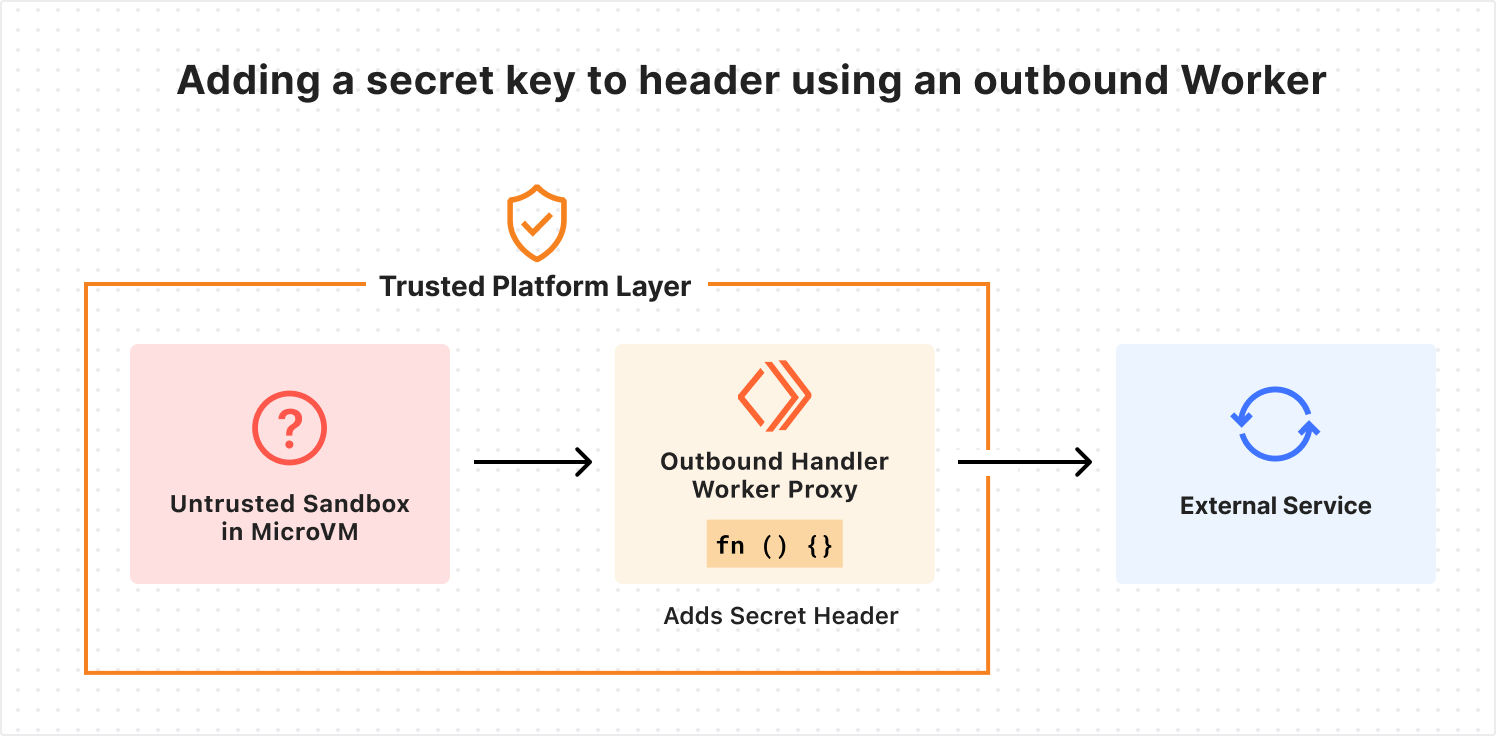
As we’ve written before, sandboxed workloads on Cloudflare can use an outbound proxy for fully dynamic, customizable, and zero-trust authentication between sandboxes and external services. This lets you inject secrets into requests outside the sandbox, so the agent never has access to them. This protects against exfiltration attacks.
And sometimes internal services shouldn’t ever be exposed to the open Internet. We recently launched Cloudflare Mesh and Cloudflare Workers VPC to better connect to these private services, whether they’re running on a cloud provider like AWS or on-premises. This allows you to connect to internal services using post-quantum encrypted networking without a VPN or bastion host.
Claude Managed Agents can easily connect to private services with header injection or private VPC/Mesh tunnels. This is done via customizable outbound proxies. You can define egress policies that expose only the services you choose to the agent sandboxes that you choose. You can allowlist specific endpoints, perform zero-trust injection of encrypted credentials, access private services via Cloudflare Mesh, and even write custom proxy middleware.
The integration uses outbound Workers to handle egress however you see fit
You’re able to apply policies per tenant, per agent, or based on whatever metadata is useful. This gives you full control over how your agents connect to external services.
Doing more with the Cloudflare Developer Platform
Agents need more than just a code execution environment. Cloudflare’s Developer Platform provides the tools you need by default to let your agents do more.
Sandboxes can make tool calls on Cloudflare and safely access external services.
Here are a few of the tools you’ll find most useful as you deploy agents on Cloudflare:
Browser Run via Claude
One of the most common tools agents need is a browser. While curl can get you pretty far, when you want an agent to act like a human, this often means interacting with the web like one: rendering JS-heavy applications, taking screenshots for QA validation, filling out forms, etc. Browser Run is Cloudflare’s tool to give agents browsers.
A Browser Run session recording lets you watch how your agents used a browser. One of many built-in tools.
The Claude Managed Agents integration ships with multiple browser-related tools that can be enabled immediately. These include browser_search, browser_execute, screenshot, browse, fetch_to_markdown, and a Cloudflare-specific implementation of web_fetch allows your agent to control a browser that runs on Cloudflare infrastructure. This not only lets your agent do more, but it also makes it easy to audit every action your agent’s browser is taking on the web, apply allowlists and denylist to browser sessions, and save recordings of browser sessions for future debugging.
Agent inboxes
The integration also comes with built-in support for email with the send_email, email_read, and email_list tools.
You can also kick off new sessions via email, or configure the agent to send emails using any domain and address configured with the Cloudflare Email Service. This allows the agent to act on your behalf when it needs to, reply to context in forwarded emails, and autonomously interact with others via email.
Custom tools and more
Other built-in tools include call_service, which uses Cloudflare Mesh or Workers VPC to connect to private services, and image_generate, which uses Workers AI to generate images on Cloudflare. This pairs well with Claude providing text-based inference.
Additionally, we encourage forking the repo to easily add customized tools. For example, you could add a custom tool to host a public file on Cloudflare’s R2 object storage. Just add the relevant binding in wrangler config, write a zod definition, and short function in custom-tools.js:
defineTool({
  name: "r2_host_file",
  description: "Upload from sandbox to R2 and get a public URL.",
  inputSchema: z.object({
    key: z.string().describe("Object key"),
    content: z.string().describe("UTF-8 file body"),
    contentType: z.string().describe("MIME type"),
  }),
  run: async ({ key, content, contentType }, { env }) => {
    await env.PUBLIC_BUCKET.put(
      key, content, { httpMetadata: { contentType }}
    );
    return `${env.PUB_R2_URL.replace(/\/$/, "")}/${encodeURI(key)}`;
  }
}),
The Cloudflare Developer Platform provides all sorts of possibilities for extending your agents: give each agent session a git-backed repo with Artifacts, run edge inference with Workers AI, host applications written on the fly with Dynamic Workers, and more.
You don’t have to worry about infrastructure or scaling – just write a few lines of code and hit deploy.
Claude + Cloudflare
We’re excited to be working together with Anthropic to bring Cloudflare’s flexibility, scale, and security to more users. Whether you want to run tens of millions of agents using isolates, securely connect to private services with Workers VPC, or write custom tools that take advantage of all of Cloudflare, our new integration makes it easy.
Today marks the end of our first Agents Week, an innovation week dedicated entirely to the age of agents. It couldn’t have been more timely: over the past year, agents have swiftly changed how people work. Coding agents are helping developers ship faster than ever. Support agents resolve tickets end-to-end. Research agents validate hypotheses across hundreds of sources in minutes. And people aren’t just running one agent: they’re running several in parallel and around the clock.
As Cloudflare’s CTO Dane Knecht and VP of Product Rita Kozlov noted in our welcome to Agents Week post, the potential scale of agents is staggering: If even a fraction of the world’s knowledge workers each run a few agents in parallel, you need compute capacity for tens of millions of simultaneous sessions. The one-app-serves-many-users model the cloud was built on doesn’t work for that. But that’s exactly what developers and businesses want to do: build agents, deploy them to users, and run them at scale.
Getting there means solving problems across the entire stack. Agents need compute that scales from full operating systems to lightweight isolates. They need security and identity built into how they run. They need an agent toolbox: the right models, tools, and context to do real work. All the code that agents generate needs a clear path from afternoon prototype to production app. And finally, as agents drive a growing share of Internet traffic, the web itself needs to adapt for the emerging agentic web. Turns out, the containerless, serverless compute platform we launched eight years ago with Workers was ready-made for this moment. Since then, we’ve grown it into a full platform, and this week we shipped the next wave of primitives purpose-built for agents, organized around exactly those problems.
We are here to create Cloud 2.0 — the agentic cloud. Infrastructure designed for a world where agents are a primary workload.
Here’s a list of everything we announced this week — we wouldn’t want you to miss a thing.
Compute
It starts with compute. Agents need somewhere to run, and somewhere to store and run the code they write. Not all agents need the same thing: some need a full operating system to install packages and run terminal commands, most need something lightweight that starts in milliseconds and scales to millions. This week we shipped the environments to run them, as well as a new Git-compatible workspace for agents:
Give your agents, developers, and automations a home for code and data. We’ve just launched Artifacts: Git-compatible versioned storage built for agents. Create tens of millions of repos, fork from any remote, and hand off a URL to any Git client.
Cloudflare Sandboxes give AI agents a persistent, isolated environment: a real computer with a shell, a filesystem, and background processes that starts on demand and picks up exactly where it left off.
Outbound Workers for Sandboxes provide a programmable, zero-trust egress proxy for AI agents. This allows developers to inject credentials and enforce dynamic security policies without exposing sensitive tokens to untrusted code.
Durable Object Facets allows Dynamic Workers to instantiate Durable Objects with their own isolated SQLite databases. This enables developers to build platforms that run persistent, stateful code generated on-the-fly.
Cloudflare Workflows, a durable execution engine for multi-step applications, now supports 50,000 concurrency and 300 creation rate limits through a rearchitectured control plane, helping scale to meet the use cases for durable background agents.
Security
Running agents and their code is only half the challenge. Agents connect to private networks, access internal services, and take autonomous actions on behalf of users. When anyone in an organization can spin up their own agents, security can’t be an afterthought. It has to be the default. This week, we launched the tools to make that easy.
Cloudflare Mesh provides secure, private network access for users, nodes, and autonomous AI agents. By integrating with Workers VPC, developers can now grant agents scoped access to private databases and APIs without manual tunnels.
Managed OAuth for Cloudflare Access helps AI agents securely navigate internal applications. By adopting RFC 9728, agents can authenticate on behalf of users without using insecure service accounts.
Cloudflare is introducing scannable API tokens, enhanced OAuth visibility, and GA for resource-scoped permissions. These tools help developers implement a true least-privilege architecture while protecting against credential leakage.
We share Cloudflare’s internal strategy for governing MCP using Access, AI Gateway, and MCP server portals. We also launch Code Mode to slash token costs and recommend new rules for detecting Shadow MCP in Cloudflare Gateway.
Agent Toolbox
A capable agent needs to be able to think and remember, communicate, and see. This means being powered with the right models, with access to the right tools and the right context for their task at hand. This week we shipped the primitives — inference, search, memory, voice, email, and a browser — that turn an agent into something that actually gets work done.
Announcing a preview of the next edition of the Agents SDK — from lightweight primitives to a batteries-included platform for AI agents that think, act, and persist.
An experimental voice pipeline for the Agents SDK enables real-time voice interactions over WebSockets. Developers can now build agents with continuous STT and TTS in just ~30 lines of server-side code.
Agents are becoming multi-channel. That means making them available wherever your users already are — including the inbox. Cloudflare Email Service enters public beta with the infrastructure layer to make that easy: send, receive, and process email natively from your agents.
We’re building Cloudflare into a unified inference layer for agents, letting developers call models from 14+ providers. New features include Workers binding for running third-party models and an expanded catalog with multimodal models.
We built a custom technology stack to run fast large language models on Cloudflare’s infrastructure. This post explores the engineering trade-offs and technical optimizations required to make high-performance AI inference accessible.
Running large LLMs across Cloudflare’s network requires us to be smarter and more efficient about GPU memory bandwidth. That’s why we developed Unweight, a lossless inference-time compression system that achieves up to a 22% model footprint reduction, so that we can deliver faster and cheaper inference than ever before.
Cloudflare Agent Memory is a managed service that gives AI agents persistent memory, allowing them to recall what matters, forget what doesn’t, and get smarter over time.
AI Search is the search primitive for your agents. Create instances dynamically, upload files, and search across instances with hybrid retrieval and relevance boosting. Just create a search instance, upload, and search.
Browser Rendering is now Browser Run, with Live View, Human in the Loop, CDP access, session recordings, and 4x higher concurrency limits for AI agents.
Prototype to production
The best infrastructure is also one that’s easy to use. We want to meet developers and their agents where they’re already working: in the terminal, in the editor, in a prompt, and make the full Cloudflare platform accessible without context-switching.
We’re introducing cf, a new unified CLI designed for consistency across the Cloudflare platform, alongside Local Explorer for debugging local data. These tools simplify how developers and AI agents interact with our nearly 3,000 API operations.
Agent Lee is an in-dashboard agent that shifts Cloudflare’s interface from manual tab-switching to a single prompt. Using sandboxed TypeScript, it helps you troubleshoot and manage your stack as a grounded technical collaborator.
Introducing Flagship, a native feature flag service built on Cloudflare’s global network to eliminate the latency of third-party providers. By using KV and Durable Objects, Flagship allows for sub-millisecond flag evaluation.
The Cloudflare Registrar API is now in beta. Developers and AI agents can search, check availability, and register domains at cost directly from their editor, their terminal, or their agent — without leaving their workflow.
Agentic Web
As more agents come online, they’re still browsing an Internet that was built for people. Existing websites need new tools to control what bots can access their content, package and present it for agents, and measure how ready they are for this shift.
The Agent Readiness score can help site owners understand how well their websites support AI agents. Here we explore new standards, share Radar data, and detail how we made Cloudflare’s docs the most agent-friendly on the web.
Soft directives don’t stop crawlers from ingesting deprecated content. Redirects for AI Training allows anybody on Cloudflare to redirect verified crawlers to canonical pages with one toggle and no origin changes.
By migrating our request handling layer to a Rust-based architecture called FL2, Cloudflare has increased its performance lead to 60% of the world’s top networks. We use real-user measurements and TCP connection trimeans to ensure our data reflects the actual experience of people on the Internet
We give you a sneak peek of our support for shared compression dictionaries, show you how it improves page load times, and reveal when you’ll be able to try the beta yourself.
That’s a wrap
Agents Week 2026 is ending, but the agentic cloud is just getting started. Everything we shipped this week — from compute and security to the agent toolbox and the agentic web — is the foundation. We’re going to keep building on it to give you everything you need to build what’s next.
We also have more blog posts coming out today and tomorrow to continue the story, so keep an eye out for the latest at our blog.
If you’re building on any of what we announced this week, we want to hear about it. Come find us on X or Discord, or head to the developer documentation.
AI is writing more code than ever. AI-assisted contributions now account for a rapidly growing share of new code across the platform. Agentic coding tools like OpenCode and Claude Code are shipping entire features in minutes.
AI-generated code entering production is only going to accelerate. But the bigger shift isn’t just speed — it’s autonomy.
Today, an AI agent writes code and a human reviews, merges, and deploys it. Tomorrow, the agent does all of that itself. The question becomes: how do you let an agent ship to production without removing every safety net?
Feature flags are the answer. An agent writes a new code path behind a flag and deploys it — the flag is off, so nothing changes for users. The agent then enables the flag for itself or a small test cohort, exercises the feature in production, and observes the results. If metrics look good, it ramps the rollout. If something breaks, it disables the flag. The human doesn’t need to be in the loop for every step — they set the boundaries, and the flag controls the blast radius.
This is the workflow feature flags were always building toward: not just decoupling deployment from release, but decoupling human attention from every stage of the shipping process. The agent moves fast because the flag makes it safe to move fast.
Today, we’re announcing Flagship — Cloudflare’s native feature flag service, built on OpenFeature, the CNCF open standard for feature flag evaluation. It works everywhere — Workers, Node.js, Bun, Deno, and the browser — but it’s fastest on Workers, where flags are evaluated within the Cloudflare network. With the Flagship binding and OpenFeature, integration looks like this:
await OpenFeature.setProviderAndWait(
    new FlagshipServerProvider({ binding: env.FLAGS })
);
Flagship is now available in closed beta.
The problem with feature flags on Workers
Many Cloudflare developers have resorted to the pragmatic workaround: hardcoding flag logic directly into their Workers. And honestly, it works well enough in the beginning. Workers deploy in seconds, so flipping a boolean in code and pushing it to production is fast enough for most situations.
But it doesn’t stay simple. One hardcoded flag becomes ten. Ten becomes fifty, owned by different teams, with no central view of what’s on or off. There’s no audit trail — when something breaks, you’re searching git blame to figure out who toggled what.
Network call to external services
Another common pattern used on workers is to make an HTTP request to an external service in the following manner:
That outbound request sits on the critical path of every single user request. It could add considerable latency depending on how far the user is from the flag service’s region.
This is a strange situation. Your application runs at the edge, milliseconds from the user. But the feature flag check forces it to reach back across the Internet to another API before it can decide what to render.
Why local evaluation doesn’t solve the problem
Some feature flag services offer a “local evaluation” SDK. Instead of calling a remote API on every request, the SDK downloads the full set of flag rules into memory and evaluates them locally. No outbound request per evaluation and the flag decision happens in-process.
On Workers, none of these assumptions hold. There is no long-lived process: a Worker isolate can be created, serve a request, and be evicted between one request and the next. A new invocation could mean re-initializing the SDK from scratch.
On a serverless platform, you need a distribution primitive that’s already at the edge, one where the caching is managed for you, reads are local, and you don’t need a persistent connection to keep things up to date.
Cloudflare KV is a great primitive for this!
How Flagship works
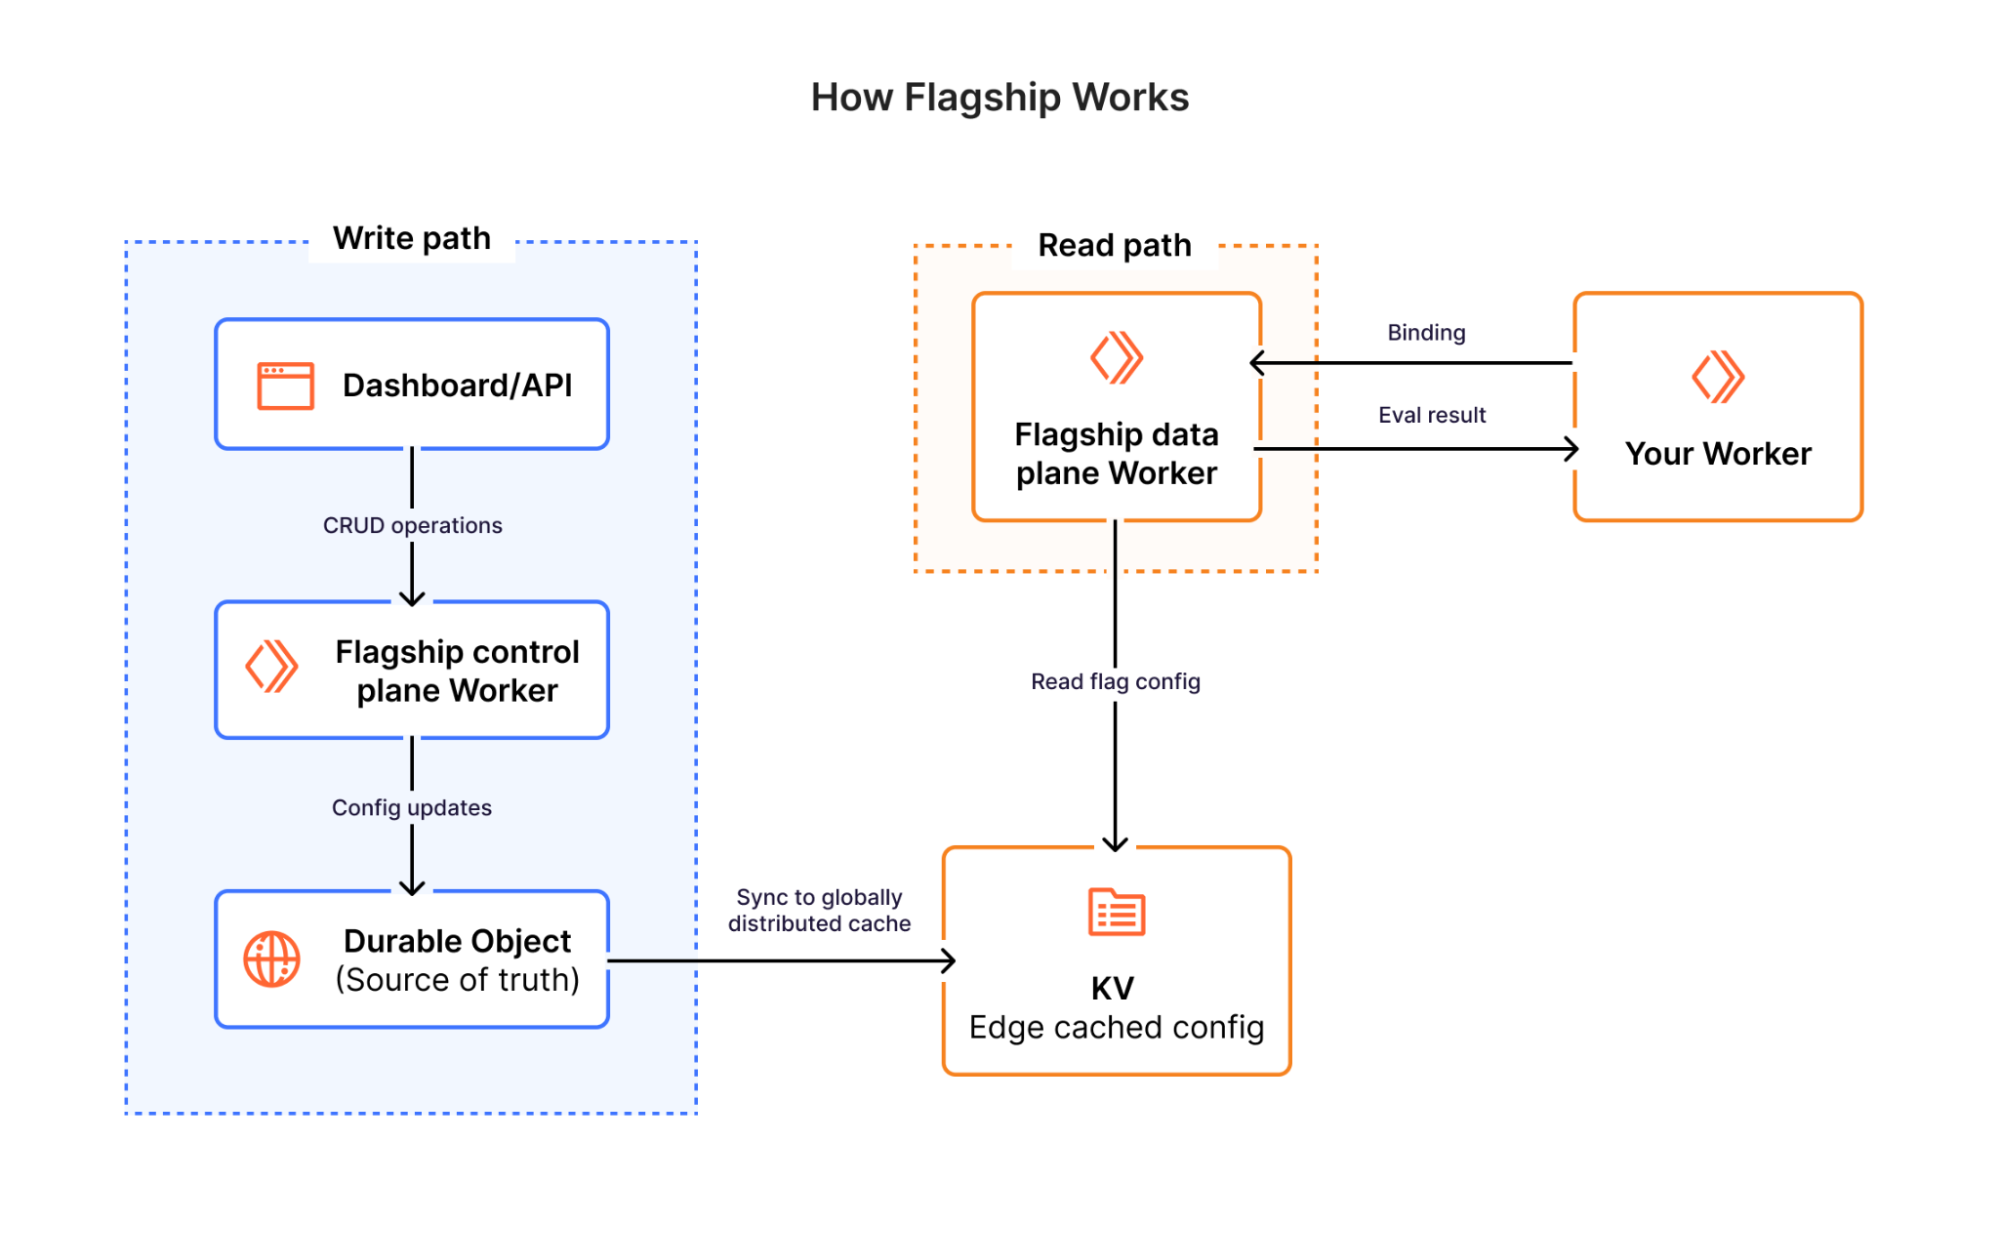
Flagship is built entirely on Cloudflare’s infrastructure — Workers, Durable Objects, and KV. There are no external databases, no third-party services, and no centralized origin servers in the evaluation path.
When you create or update a flag, the control plane writes the change atomically to a Durable Object — a SQLite-backed, globally unique instance that serves as the source of truth for that app’s flag configuration and changelog. Within seconds, the updated flag config is synced to Workers KV, Cloudflare’s globally distributed key-value store, where it’s replicated across Cloudflare’s network.
When a request evaluates a flag, Flagship reads the flag config directly from KV at the edge — the same Cloudflare location already handling the request. The evaluation engine then runs right there in an isolate: it matches the request context against the flag’s targeting rules, resolves the rollout percentage, and returns a variation. Both the data and the logic live at the edge — nothing is sent elsewhere to be evaluated.
Using Flagship: the Worker binding
For teams running Cloudflare Workers, Flagship offers a direct binding that evaluates flags inside the Workers runtime — no HTTP round-trip, no SDK overhead. Add the binding to your wrangler.jsonc and your Worker is connected:
That’s it. Your account ID is inferred from your Cloudflare account, and the app_id ties the binding to a specific Flagship app. In your Worker, you just ask for a flag value:
The binding supports typed accessors for every variation type – getBooleanValue(), getStringValue(), getNumberValue(), getObjectValue() – plus *Details() variants that return the resolved value alongside the matched variant and the reason it was selected. On evaluation errors, the default value is returned gracefully. On type mismatches, the binding throws an exception — that’s a bug in your code, not a transient failure.
The SDK: OpenFeature-native
Most feature flag SDKs come with their own interfaces and evaluation patterns. Over time, those become deeply embedded in your codebase — and switching providers means rewriting every call site.
We didn’t want to build another one of those. Flagship is built on OpenFeature, the CNCF open standard for feature flag evaluation. OpenFeature defines a common interface for flag evaluation across languages and providers — it’s the same relationship that OpenTelemetry has to observability. You write your evaluation code once against the standard, and swap providers by changing a single line of configuration.
If you’re running on Workers with the Flagship binding, you can pass it directly to the OpenFeature provider. The binding already carries your account context, so there’s nothing to configure — authentication is implicit.
Your evaluation code doesn’t change — the OpenFeature interface is identical. But under the hood, Flagship evaluates flags through the binding instead of over HTTP. You get the portability of the standard with the performance of the binding.
A client-side provider is also available for browsers. It pre-fetches the flags you specify, caches them with a configurable TTL, and serves evaluations synchronously from that cache.
What you can do with Flagship
Flagship supports the patterns you’d expect from a feature flag service and the ones that become critical when AI-generated code is landing in production daily.
Flag values can be boolean, strings, numbers, or full JSON objects — useful for configuration blocks, UI theme definitions, or routing users to different API versions without maintaining separate code paths.
Targeting Rules
Each flag can have multiple rules, evaluated in priority order. The first rule that matches wins.
A rule consists of:
Conditions that determine whether the rule applies to a given context
A flag variation to serve when the rule matches
An optional rollout for percentage-based delivery
A priority that determines evaluation order when multiple rules are present (lower number = higher priority)
Nested Logical Conditions
Conditions can be composed using AND/OR logic, nested up to five levels deep. A single rule can express things like:
(plan == “enterprise” AND region == “us” ) OR (user.email.endsWith(“@cloudflare.com”))
= serve (“premium”)
At the top level of a rule, multiple conditions are combined with implicit AND where all conditions must pass for the rule to match. Within each condition, you can nest AND/OR groups for more complex logic.
Flag Rollouts by Percentage
Unlike gradual deployments, which split traffic between different uploaded versions of your Worker, feature flags let you roll out behavior by percentage within a single version that is serving 100% of traffic.
Any rule can include a percentage rollout. Instead of serving a variation to everyone who matches the conditions, you serve it to a percentage of them.
Rollouts use consistent hashing on the specified context attribute. The same attribute value (userId, for example) always hashes to the same bucket, so they won’t flip between variations across requests. You can ramp from 5% to 10% to 50% to 100% of users, so those who were already in the rollout stay in it.
Built for what comes next
AI-generated code entering production is only going to accelerate. Agentic workflows will push it further — agents that autonomously deploy, test, and iterate on code in production. The teams that thrive in this world won’t be the ones shipping the fastest. They’ll be the ones who can ship fast and still maintain control over what their users see, roll back in seconds when something breaks, and gradually expose new code paths with confidence.
That’s what Flagship is built for:
Evaluation across region Earth, cached globally using K/V.
A full audit trail. Every flag change is recorded with field-level diffs, so you know who changed what and when.
Dashboard integration. Anyone on the team can toggle a flag or adjust a rollout without touching code.
OpenFeature compatibility. Adopt Flagship without rewriting your evaluation code. Leave without rewriting it either.
Get started with Flagship
Starting today, Flagship is in private beta. You can request for access here. We’ll share more details on pricing as we approach general availability.
Install the SDK: npm i @cloudflare/flagship; or use the Worker binding directly in your Worker
Read the documentation for integration guides and API reference
Check out the source code for examples and to contribute
If you’re currently hardcoding flags in your Workers, or evaluating flags through an external service that adds latency to every request, give Flagship a try. We’d love to hear what you build.
For many of us, our first experiences with AI agents have been through typing into a chat box. And for those of us using agents day to day, we have likely gotten very good at writing detailed prompts or markdown files to guide them.
But some of the moments where agents would be most useful are not always text-first. You might be on a long commute, juggling a few open sessions, or just wanting to speak naturally to an agent, have it speak back, and continue the interaction.
Adding voice to an agent should not require moving that agent into a separate voice framework. Today, we are releasing an experimental voice pipeline for the Agents SDK.
With @cloudflare/voice, you can add real-time voice to the same Agent architecture you already use. Voice just becomes another way you can talk to the same Durable Object, with the same tools, persistence, and WebSocket connection model that the Agents SDK already provides.
@cloudflare/voice is an experimental package for the Agents SDK that provides:
withVoice(Agent) for full conversation voice agents
withVoiceInput(Agent) for speech-to-text-only use cases, like dictation or voice search
useVoiceAgent and useVoiceInput hooks for React apps
VoiceClient for framework-agnostic clients
Built-in Workers AI providers, so that you can get started without external API keys:
This means you can now build an agent that users can talk to in real time over a single WebSocket connection, while keeping the same Agent class, Durable Object instance, and the same SQLite-backed conversation history.
Just as importantly, we want this to be bigger than one fixed default stack. The provider interfaces in @cloudflare/voice are intentionally small, and we want speech, telephony, and transport providers to build with us, so developers can mix and match the right components for their use case, instead of being locked into a single voice architecture.
Get started with voice
Here’s the minimal server-side pattern for a voice agent in the Agents SDK:
Here’s how the pipeline breaks down, step by step:
Audio transport: The browser captures microphone audio and streams 16 kHz mono PCM over the same WebSocket connection the agent already uses.
STT session setup: When the call starts, the agent creates a continuous transcriber session that lives for the duration of the call.
STT input: Audio streams continuously into that session.
STT turn detection: The speech-to-text model itself decides when the user has finished an utterance and emits a stable transcript for that turn.
LLM/application logic: The voice pipeline passes that transcript to your onTurn() method.
TTS output: Your response is synthesized to audio and sent back to the client. If onTurn() returns a stream, the pipeline sentence-chunks it and starts sending audio as sentences are ready.
Persistence: The user and agent messages are persisted in SQLite, so conversation history survives reconnections and deployments.
Why voice should grow with the rest of your agent
Many voice frameworks focus on the voice loop itself: audio in, transcription, model response, audio out. Those are important primitives, but there’s a lot more to an agent than just voice.
Real agents running in production will grow. They need state, scheduling, persistence, tools, workflows, telephony, and ways to keep all of that consistent across channels. As your agent grows in complexity, voice stops being a standalone feature and becomes part of a larger system.
We wanted voice in the Agents SDK to start from that assumption. Instead of building voice as a separate stack, we built it on top of the same Durable Object-based agent platform, so you can pull in the rest of the primitives you need without re-architecting the application later.
Voice and text share the same state
A user might start by typing, switch to voice, and go back to text. With Agents SDK, these are all just different inputs to the same agent. The same conversation history lives in SQLite, and the same tools are available. This gives you both a cleaner mental model and a much simpler application architecture to reason about.
Lower latency comes from…
a shorter network path
Voice experiences feel good or bad very quickly. Once a user stops speaking, the system needs to transcribe, think, and start speaking back fast enough to feel conversational.
A lot of voice latency is not pure model time. It’s the cost of bouncing audio and text between different services in different places. Audio needs to go to STT, transcripts go to an LLM, and responses go to a TTS model – and each handoff adds network overhead.
With the Agents SDK voice pipeline, the agent runs on Cloudflare’s network, and the built-in providers use Workers AI bindings. That keeps the pipeline tighter and reduces the amount of infrastructure you have to stitch together yourself.
built-in streaming
A voice agent interaction feels much more natural if it speaks the first sentence quickly (also called Time-to-First Audio). When onTurn() returns a stream, the pipeline chunks it into sentences and starts synthesis as sentences complete. That means the user can hear the beginning of the answer while the rest is still being generated.
A more realistic backend
Here is a fuller example that streams an LLM response and starts speaking it back, sentence by sentence:
import { Agent, routeAgentRequest } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAITTS,
  type VoiceTurnContext
} from "@cloudflare/voice";
import { streamText } from "ai";
import { createWorkersAI } from "workers-ai-provider";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async onTurn(transcript: string, context: VoiceTurnContext) {
    const ai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: ai("@cf/cloudflare/gpt-oss-20b"),
      system: "You are a helpful voice assistant. Be concise.",
      messages: [
        ...context.messages.map((m) => ({
          role: m.role as "user" | "assistant",
          content: m.content
        })),
        { role: "user" as const, content: transcript }
      ],
      abortSignal: context.signal
    });

    return result.textStream;
  }
}

export default {
  async fetch(request: Request, env: Env) {
    return (
      (await routeAgentRequest(request, env)) ??
      new Response("Not found", { status: 404 })
    );
  }
} satisfies ExportedHandler<Env>;
Context.messages gives you recent SQLite-backed conversation history, and context.signal lets the pipeline abort the LLM call if the user interrupts.
Voice as an input: withVoiceInput
Not every speech interface needs to speak back. Sometimes you might want dictation, transcription, or voice search. For these use cases, you can use withVoiceInput
import { Agent, type Connection } from "agents";
import { withVoiceInput, WorkersAINova3STT } from "@cloudflare/voice";

const InputAgent = withVoiceInput(Agent);

export class DictationAgent extends InputAgent<Env> {
  transcriber = new WorkersAINova3STT(this.env.AI);

  onTranscript(text: string, _connection: Connection) {
    console.log("User said:", text);
  }
}
On the client, useVoiceInput gives you a lightweight interface centered on transcriptions:
This is useful when speech is an input method, and you don’t need a full conversational loop.
Voice and text on the same connection
The same client can call sendText(“What’s the weather?”), which bypasses STT and sends the text directly to onTurn(). During an active call, the response can be spoken and shown as text. Outside a call, it can remain text-only.
This gives you a genuinely multimodal agent, without splitting the implementation into different code paths.
What else can you build?
Because a voice agent is still an agent, all the normal Agents SDK capabilities still apply.
Tools and scheduling
You can greet a caller when a session starts:
import { Agent, type Connection } from "agents";
import { withVoice, WorkersAIFluxSTT, WorkersAITTS } from "@cloudflare/voice";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async onTurn(transcript: string) {
    return `You said: ${transcript}`;
  }

  async onCallStart(connection: Connection) {
    await this.speak(connection, "Hi! How can I help you today?");
  }
}
You can schedule spoken reminders and expose tools to your LLM just like any other agent:
import { Agent } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAITTS,
  type VoiceTurnContext
} from "@cloudflare/voice";
import { streamText, tool } from "ai";
import { createWorkersAI } from "workers-ai-provider";
import { z } from "zod";

const VoiceAgent = withVoice(Agent);

export class MyAgent extends VoiceAgent<Env> {
  transcriber = new WorkersAIFluxSTT(this.env.AI);
  tts = new WorkersAITTS(this.env.AI);

  async speakReminder(payload: { message: string }) {
    await this.speakAll(`Reminder: ${payload.message}`);
  }

  async onTurn(transcript: string, context: VoiceTurnContext) {
    const ai = createWorkersAI({ binding: this.env.AI });

    const result = streamText({
      model: ai("@cf/cloudflare/gpt-oss-20b"),
      messages: [
        ...context.messages.map((m) => ({
          role: m.role as "user" | "assistant",
          content: m.content
        })),
        { role: "user" as const, content: transcript }
      ],
      tools: {
        set_reminder: tool({
          description: "Set a spoken reminder after a delay",
          inputSchema: z.object({
            message: z.string(),
            delay_seconds: z.number()
          }),
          execute: async ({ message, delay_seconds }) => {
            await this.schedule(delay_seconds, "speakReminder", { message });
            return { confirmed: true };
          }
        })
      },
      abortSignal: context.signal
    });

    return result.textStream;
  }
}
Runtime model switching
The voice pipeline also lets you choose a transcription model dynamically per connection.
For example, you might prefer Flux for conversational turn-taking and Nova 3 for higher-accuracy dictation. You can switch at runtime by overriding createTranscriber():
import { Agent, type Connection } from "agents";
import {
  withVoice,
  WorkersAIFluxSTT,
  WorkersAINova3STT,
  WorkersAITTS,
  type Transcriber
} from "@cloudflare/voice";

export class MyAgent extends VoiceAgent<Env> {
  tts = new WorkersAITTS(this.env.AI);

  createTranscriber(connection: Connection): Transcriber {
    const url = new URL(connection.url ?? "http://localhost");
    const model = url.searchParams.get("model");
    if (model === "nova-3") {
      return new WorkersAINova3STT(this.env.AI);
    }
    return new WorkersAIFluxSTT(this.env.AI);
  }
}
On the client, you can pass query parameters through the hook:
This lets the same agent handle web voice, text input, and phone calls.
One caveat: the default Workers AI TTS provider returns MP3, while Twilio expects mulaw 8kHz audio. For production telephony, you may want to use a TTS provider that outputs PCM or mulaw directly.
WebRTC
If you need a transport that is better suited to difficult network conditions or will include multiple participants, the voice package also includes SFU utilities and supports custom transports. The default model is WebSocket-native today, but we plan to develop more adapters to connect to our global SFU infrastructure.
Build with us
The voice pipeline is provider-agnostic by design.
Under the hood, each stage is defined by a small interface: a transcriber opens a continuous session and accepts audio frames as they arrive, while a TTS provider takes text and returns audio. If a provider can stream audio output, the pipeline can use that too.
We didn’t want voice support in Agents SDK to only work with one fixed combination of models and transports. We wanted the default path to be simple, while still making it easy to plug in other providers as the ecosystem grows.
The built-in providers use Workers AI, so you can get started without external API keys:
WorkersAIFluxSTT for conversational streaming STT
WorkersAINova3STT for dictation-style streaming STT
WorkersAITTS for text-to-speech
But the bigger goal is interoperability. If you maintain a speech or voice service, these interfaces are small enough to implement without needing to understand the rest of the SDK internals. If your STT provider accepts streaming audio and can detect utterance boundaries, it can satisfy the transcriber interface. If your TTS provider can stream audio output, even better.
We would love to work on interoperability with:
STT providers like AssemblyAI, Rev.ai, Speechmatics, or any service with a real-time transcription API
TTS providers like PlayHT, LMNT, Cartesia, Coqui, Amazon Polly, or Google Cloud TTS
telephony adapters for platforms like Vonage, Telnyx, or Bandwidth
transport implementations for WebRTC data channels, SFU bridges, and other audio transport layers
We are also interested in collaborations that go beyond individual providers:
latency benchmarking across STT + LLM + TTS combinations
multilingual support and better documentation for non-English voice agents
accessibility work, especially around multimodal interfaces and speech impairments
If you are building voice infrastructure and want to see a first-class integration, open a PR or reach out.
Try it now
The voice pipeline is available today as an experimental package:
Add @cloudflare/voice, give your agent a transcriber and a TTS provider, deploy it, and start talking to it. You can also read the API reference.
If you build something interesting, open an issue or PR on github.com/cloudflare/agents. Voice should not require a separate stack, and we think the best voice agents will be the ones built on the same durable application model as everything else.
When we originally built Workflows, our durable execution engine for multi-step applications, it was designed for a world in which workflows were triggered by human actions, like a user signing up or placing an order. For use cases like onboarding flows, workflows only had to support one instance per person — and people can only click so fast.
Over time, what we’ve actually seen is a quantitative shift in the workload and access pattern: fewer human-triggered workflows, and more agent-triggered workflows, created at machine speed.
As agents become persistent and autonomous infrastructure, operating on behalf of users for hours or days, they need a durable, asynchronous execution engine for the work they are doing. Workflows provides exactly that: every step is independently retryable, the workflow can pause for human-in-the-loop approval, and each instance survives failures without losing progress.
Moreover, workflows themselves are being used to implement agent loops and serve as the durable harnesses that manage and keep agents alive. OurAgents SDK integration accelerated this, making it easy for agents to spawn workflow instances and get real-time progress back. A single agent session can now kick off dozens of workflows, and many agents running concurrently means thousands of instances created in seconds. With Project Think now available, we anticipate that velocity will only increase.
To help developers scale their agents and applications on Workflows, we are excited to announce that we now support:
50,000 concurrent instances (number of workflow executions running in parallel), originally 4,500
300 instances/second created per account, previously 100
2 million queued instances (meaning instances that have been created or awoken and are waiting for a concurrency slot) per workflow, up from 1 million
We redesigned the Workflows control plane from usage data and first principles to support these increases. For V1 of the control plane, a single Durable Object (DO) could serve as the central registry and coordinator of an entire account. For V2, we built two new components to help horizontally scale the system and alleviate the bottlenecks that V1 introduced, before migrating all customers — with live traffic — seamlessly onto the new version.
V1: initial architecture of Workflows
As described in our public beta blog post, we built Workflows entirely on our own developer platform. Fundamentally, a workflow is a series of durable steps, each independently retryable, that can execute tasks, wait for external events, or sleep until a predetermined time.
To trigger each instance, execute its logic, and store its metadata, we leverage SQLite-backed Durable Objects, which are a simple but powerful primitive for coordination and storage within a distributed system.
In the control plane, some Durable Objects — like the Engine, which executes the actual workflow instance, including its step, retry, and sleep logic — are spun up at a ratio of 1:1 per instance. On the other hand, the Account is an account-level Durable Object that manages all workflows and workflow instances for that account.
After we launched Workflows into beta, we were thrilled to see customers quickly scaling their use of the product, but we also realized that having a single Durable Object to store all that account-level information introduced a bottleneck. Many customers needed to create and execute hundreds or even thousands of Workflow instances per minute, which could quickly overwhelm the Account in our original architecture. The original rate limits — 4,500 concurrency slots and 100 instance creations per 10 seconds — were a result of this limitation.
On the V1 control plane, these limits were a hard cap. Any and all operations depending on Account, including create, update, and list, had to go through that single DO. Users with high concurrency workloads could have thousands of instances starting and ending at any given moment, building up to thousands of requests per second to Account. To solve for this, we rearchitected the workflow control plane such that it horizontally scales to higher concurrency and creation rate limits.
V2: horizontal scale for higher throughput
For the new version, we rethought every single operation from the ground up with the goal of optimizing for high-volume workflows. Ultimately, Workflows should scale to support whatever developers need – whether that is thousands of instances created per second or millions of instances running at a time. We also wanted to ensure that V2 allowed for flexible limits, which we can toggle and continue increasing, rather than the hard cap which V1 limits imposed. After many design iterations, we settled on the following pillars for our new architecture:
The source of truth for the existence of a given instance should be its Engine and nothing else.
In the V1 control plane architecture, we lacked a check before queuing the instance as to whether its Engine actually existed. This allowed for a bad state where an instance may have been queued without its corresponding Engine having spun up.
Instance lifecycle and liveness mechanisms must be horizontally scalable per-workflow and distributed throughout many regions.
The new Account singleton should only store the minimum necessary metadata and have an invariant maximum amount of concurrent requests.
There are two new, critical components in the V2 control plane which allowed us to improve the scalability of Workflows: SousChef and Gatekeeper. The first component, SousChef, is a “second in command” to the Account. Recall that previously, the Account managed the metadata and lifecycle for all of the instances across all of the workflows within a given account. SousChef was introduced to keep track of metadata and lifecycle on a subset of instances in a given workflow. Within an account, a distribution of SousChefs can then report back to Account in a more efficient and manageable way. (An added benefit of this design: not only did we already have per-account isolation, but we also inadvertently gained “per-workflow” isolation within the same account, since each SousChef only takes care of one specific workflow).
The second component, Gatekeeper, is a mechanism to distribute concurrency “slots” (derived from concurrency limits) across all SousChefs within the account. It acts as a leasing system. When an instance is created, it is randomly assigned to one of the SousChefs within that account. Then the SousChef makes a request to Account to trigger that instance. Either a slot is granted, or the instance is queued. Once the slot is granted, the SousChef triggers execution of the instance and assumes responsibility that the instance never gets stuck.
Gatekeeper was needed to make sure that Engines never overloaded their Account (a pressing risk on V1) so every communication between SousChefs and their Account happens on a periodic cycle, once per second — each cycle will also batch all slot requests, ensuring that only one JSRPC call is made. This ensures the instance creation rate can never overload or influence the most important component, Account (as an aside: if the SousChef count is too high, we rate-limit calls or spread across different SousChefs throughout different time periods). Also, this periodic property allows us to preserve fairness on older instances and to ensure max-min fairness through the many SousChefs, allowing them all to progress. For example, if an instance wakes up, it should be prioritized for a slot over a newly created instance, but each SousChef ensures that its own instances do not get stuck.
This architecture is more distributed, and therefore, more scalable. Now, when an instance is created, the request path is:
Check control plane version
Check if a cached version of the workflow and version details is available in that location
If not, check Account to get workflow name, unique ID, and version, and cache that information
Store only necessary metadata (instance payload, creation date) onto its own Engine
So, how does Engine tell the control plane that it now exists? That happens in the background after instance metadata is set. As background operations on a Durable Object can fail, due to eviction or server failure, we also set an “alarm” on Engine in the creation hot-path. That way, if the background task does not finish, the alarm ensures that the instance will begin.
A Durable Object alarm allows a Durable Object instance to be awakened at a fine-grained time in the future with an at-least-once execution model, with automatic retries built in. We extensively use this combination of background “tasks” and alarms to remove operations off the hot-path while still ensuring that everything will happen as planned. That’s how we keep critical operations like creating an instance fast without ever compromising on reliability.
Other than unlocking scale, this version of the control plane means that:
Instance listing performance is faster, and actually consistent with cursor pagination;
Any operation on an instance does exactly one network hop (as it can go directly to its Engine, ensuring that eyeball request latency is as small as we can manage);
We can ensure that more instances are actually behaving correctly (by running on time) concurrently (and correct them if not, making sure that Engines are never late to continue execution).
V1 → V2 migration
Now that we had a new version of the Workflows control plane that can handle a higher volume of user load, we needed to do the “boring” part: migrating our customers and instances to the new system. At Cloudflare’s scale, this becomes a problem in and of itself, so the “boring” part becomes the biggest challenge. Well before its one-year mark, Workflows had already racked up millions of instances and thousands of customers. Also, some tech debt on V1’s control plane meant that a queued instance might not have its own Engine Durable Object created yet, complicating matters further.
Such a migration is tricky because customers might have instances running at any given moment; we needed a way to add the SousChef and Gatekeeper components into older accounts without causing any disruption or downtime.
We ultimately decided that we would migrate existing Accounts (which we’ll refer to as AccountOlds) to behave like SousChefs. By persisting the Account DOs, we maintained the instance metadata, and simply converted the DO into a SousChef “DO”:
// You might be wondering what's this SousChef class? This is the SousChef DO class!
import { SousChef } from "@repo/souschef";

class AccountOld extends DurableObject {
  constructor(state: DurableObjectState, env: Env) {
    // We added the following snippet to the end of our AccountOld DO's
    // constructor. This ensures that if we want, we can use any primitive
    // that is available on SousChef DO
    if (this.currentVersion === ControlPlaneVersions.SOUS_CHEFS) {
      this.sousChef = new SousChef(this.ctx, this.env);
      await this.sousChef.setup()
    }
  }

  async updateInstance(params: UpdateInstanceParams) {
    if (this.currentVersion === ControlPlaneVersions.SOUS_CHEFS) {
      assert(this.sousChef !== undefined, 'SousChef must exist on v2');
      return this.sousChef.updateInstance(params);
    }

    // old logic remains the same
  }

  @RequiresVersion<AccountOld>(ControlPlaneVersions.V1)
  async getMetadata() {
    // this method can only be run if
    // this.currentVersion === ControlPlaneVersions.V1
  }
}
We can instantiate the SousChef class within the AccountOld because the SQL tables that track instance metadata, on both SousChefs and AccountOld DOs, are the same on both. As such, we could just decide which version of the code to use. If this hadn’t been the case, we would have been forced to migrate the metadata of millions of instances, which would have made the migration more difficult and longer running for each account. So, how did the migration work?
First, we prepared AccountOld DOs to be switched to behave as SousChefs (which meant creating a release with a version of the snippet above). Then, we enabled control plane V2 per account, which triggered the next three steps roughly at the same time:
All new instance creation requests are now routed to the new SousChefs (SousChefs are created when they receive the first request), new instances never go to AccountOld again;
AccountOld DOs start migrating themselves to behave like SousChefs;
The new Account DO is spun up with the corresponding metadata.
After all accounts were migrated to the new control plane version, we were able to sunset AccountOld DOs as their instance retention periods expired. Once all instances on all accounts on AccountOlds were migrated, we could spin down those DOs permanently. The migration was completed with no downtime in a process that truly felt like changing a car’s wheels while driving.
If your use case requires higher limits than our new defaults — a concurrency limit of 50,000 slots and account-level creation rate limit of 300 instances per second, 100 per workflow — reach out via your account team or the Workers Limit Request Form. You can also reach out with feedback, feature requests, or just to share how you are using Workflows on our Discord server.
Today, we’re introducing Project Think: the next generation of the Agents SDK. Project Think is a set of new primitives for building long-running agents (durable execution, sub-agents, sandboxed code execution, persistent sessions) and an opinionated base class that wires them all together. Use the primitives to build exactly what you need, or use the base class to get started fast.
Something happened earlier this year that changed how we think about AI. Tools like Pi, OpenClaw, Claude Code, and Codex proved a simple but powerful idea: give an LLM the ability to read files, write code, execute it, and remember what it learned, and you get something that looks less like a developer tool and more like a general-purpose assistant.
These coding agents aren’t just writing code anymore. People are using them to manage calendars, analyze datasets, negotiate purchases, file taxes, and automate entire business workflows. The pattern is always the same: the agent reads context, reasons about it, writes code to take action, observes the result, and iterates. Code is the universal medium of action.
Our team has been using these coding agents every day. And we kept running into the same walls:
They only run on your laptop or an expensive VPS: there’s no sharing, no collaboration, no handoff between devices.
They’re expensive when idle: a fixed monthly cost whether the agent is working or not. Scale that to a team, or a company, and it adds up fast.
They require management and manual setup: installing dependencies, managing updates, configuring identity and secrets.
And there’s a deeper structural issue. Traditional applications serve many users from one instance. As mentioned in our Welcome to Agents Week post, agents are one-to-one. Each agent is a unique instance, serving one user, running one task. A restaurant has a menu and a kitchen optimized to churn out dishes at volume. An agent is more like a personal chef: different ingredients, different techniques, different tools every time.
That fundamentally changes the scaling math. If a hundred million knowledge workers each use an agentic assistant at even modest concurrency, you need capacity for tens of millions of simultaneous sessions. At current per-container costs, that’s unsustainable. We need a different foundation.
That’s what we’ve been building.
Introducing Project Think
Project Think ships a set of new primitives for the Agents SDK:
Durable execution with fibers: crash recovery, checkpointing, automatic keepalive
Sub-agents: isolated child agents with their own SQLite and typed RPC
The execution ladder: workspace, isolate, npm, browser, sandbox
Self-authored extensions: agents that write their own tools at runtime
Each of these is usable directly with the Agent base class. Build exactly what you need with the primitives, or use the Think base class to get started fast. Let’s look at what each one does.
Long-running agents
Agents, as they exist today, are ephemeral. They run for a session, tied to a single process or device, and then they are gone. A coding agent that dies when your laptop sleeps, that’s a tool. An agent that persists — that can wake up on demand, continue work after interruptions, and carry forward the state without depending on your local runtime — that starts to look like infrastructure. And it changes the scaling model for agents completely.
The Agents SDK builds on Durable Objects to give every agent an identity, persistent state, and the ability to wake on message. This is the actor model: each agent is an addressable entity with its own SQLite database. It consumes zero compute when hibernated. When something happens (an HTTP request, a WebSocket message, a scheduled alarm, an inbound email) the platform wakes the agent, loads its state, and hands it the event. The agent does its work, then goes back to sleep.
VMs / Containers
Durable Objects
Idle cost
Full compute cost, always
Zero (hibernated)
Scaling
Provision and manage capacity
Automatic, per-agent
State
External database required
Built-in SQLite
Recovery
You build it (process managers, health checks)
Platform restarts, state survives
Identity / routing
You build it (load balancers, sticky sessions)
Built-in (name → agent)
10,000 agents, each active 1% of the time
10,000 always-on instances
~100 active at any moment
This changes the economics of running agents at scale. Instead of “one expensive agent per power user,” you can build “one agent per customer” or “one agent per task” or “one agent per email thread.” The marginal cost of spawning a new agent is effectively zero.
Surviving crashes: durable execution with fibers
An LLM call takes 30 seconds. A multi-turn agent loop can run for much longer. At any point during that window, the execution environment can vanish: a deploy, a platform restart, hitting resource limits. The upstream connection to the model provider is severed permanently, in-memory state is lost, and connected clients see the stream stop with no explanation.
runFiber() solves this. A fiber is a durable function invocation: registered in SQLite before execution begins, checkpointable at any point via stash(), and recoverable on restart via onFiberRecovered.
import { Agent } from "agents";

export class ResearchAgent extends Agent {
  async startResearch(topic: string) {
    void this.runFiber("research", async (ctx) => {
      const findings = [];

      for (let i = 0; i < 10; i++) {
        const result = await this.callLLM(`Research step ${i}: ${topic}`);
        findings.push(result);

        // Checkpoint: if evicted, we resume from here
        ctx.stash({ findings, step: i, topic });

        this.broadcast({ type: "progress", step: i });
      }

      return { findings };
    });
  }

  async onFiberRecovered(ctx) {
    if (ctx.name === "research" && ctx.snapshot) {
      const { topic } = ctx.snapshot;
      await this.startResearch(topic);
    }
  }
}
The SDK keeps the agent alive automatically during fiber execution, no special configuration needed. For work measured in minutes, keepAlive() / keepAliveWhile() prevents eviction during active work. For longer operations (CI pipelines, design reviews, video generation) the agent starts the work, persists the job ID, hibernates, and wakes on callback.
Delegating work: sub-agents via Facets
A single agent shouldn’t do everything itself. Sub-agents are child Durable Objects colocated with the parent via Facets, each with their own isolated SQLite and execution context:
Sub-agents are isolated at the storage level. Each one gets its own SQLite database, and there’s no implicit sharing of data between them. This is enforced by the runtime where sub-agent RPC latency is a function call. TypeScript catches misuse at compile time.
Conversations that persist: the Session API
Agents that run for days or weeks need more than the typical flat list of messages. The experimental Session API models this explicitly. Available on the Agent base class, conversations are stored as trees, where each message has a parent_id. This enables forking (explore an alternative without losing the original path), non-destructive compaction (summarize older messages rather than deleting them), and full-text search across conversation history via FTS5.
Session is usable directly with Agent, and it’s the storage layer that the Think base class builds on.
From tool calls to code execution
Conventional tool-calling has an awkward shape. The model calls a tool, pulls the result back through the context window, calls another tool, pulls that back, and so on. As the tool surface grows, this gets both expensive and clumsy. A hundred files means a hundred round-trips through the model.
// The LLM writes this. It runs in a sandboxed Dynamic Worker.
const files = await tools.find({ pattern: "**/*.ts" });
const results = [];
for (const file of files) {
  const content = await tools.read({ path: file });
  if (content.includes("TODO")) {
    results.push({ file, todos: content.match(/\/\/ TODO:.*/g) });
  }
}
return results;
Instead of 100 round-trips to the model, you just run a single program. This leads to fewer tokens used, faster execution, and better results. The Cloudflare API MCP server demonstrates this at scale. We expose only two tools (search() and execute()), which consume ~1,000 tokens, vs. ~1.17 million tokens for the naive tool-per-endpoint equivalent. This is a 99.9% reduction.
The missing primitive: safe sandboxes
Once you accept that models should write code on behalf of users, the question becomes: where does that code run? Not eventually, not after a product team turns it into a roadmap item. Right now, for this user, against this system, with tightly defined permissions.
Dynamic Workers are that sandbox. A fresh V8 isolate spun up at runtime, in milliseconds, with a few megabytes of memory. That’s roughly 100x faster and up to 100x more memory-efficient than a container. You can start a new one for every single request, run a snippet of code, and throw it away.
The critical design choice is the capability model. Instead of starting with a general-purpose machine and trying to constrain it, Dynamic Workers begin with almost no ambient authority (globalOutbound: null, no network access) and the developer grants capabilities explicitly, resource by resource, through bindings. We go from asking “how do we stop this thing from doing too much?” to “what exactly do we want this thing to be able to do?”
This is the right question for agent infrastructure.
The execution ladder
This capability model leads naturally to a spectrum of compute environments, an execution ladder that the agent escalates through as needed:
Tier 0 is the Workspace, a durable virtual filesystem backed by SQLite and R2. Read, write, edit, search, grep, diff. Powered by @cloudflare/shell.
Tier 1 is a Dynamic Worker: LLM-generated JavaScript running in a sandboxed isolate with no network access. Powered by @cloudflare/codemode.
Tier 2 adds npm. @cloudflare/worker-bundler fetches packages from the registry, bundles them with esbuild, and loads the result into the Dynamic Worker. The agent writes import { z } from "zod" and it just works.
Tier 3 is a headless browser via Cloudflare Browser Run. Navigate, click, extract, screenshot. Useful when the service doesn’t support agents yet via MCP or APIs.
Tier 4 is a Cloudflare Sandbox configured with your toolchains, repos, and dependencies: git clone, npm test, cargo build, synced bidirectionally with the Workspace.
The key design principle: the agent should be useful at Tier 0 alone, where each tier is additive. The user can add capabilities as they go.
Building blocks, not a framework
All of these primitives are available as standalone packages. Dynamic Workers, @cloudflare/codemode, @cloudflare/worker-bundler, and @cloudflare/shell (a durable filesystem with tools) are all usable directly with the Agent base class. You can combine them to give any agent a workspace, code execution, and runtime package resolution without adopting an opinionated framework.
The platform
Here’s the complete stack for building agents on Cloudflare:
Each of these is a building block. Together, they form something new: a platform where anyone can build, deploy, and run AI agents as capable as the ones running on your local machine today, but serverless, durable, and safe by construction.
The Think base class
Now that you’ve seen the primitives, here’s what happens when you wire them all together.
Think is an opinionated harness that handles the full chat lifecycle: agentic loop, message persistence, streaming, tool execution, stream resumption, and extensions. You focus on what makes your agent unique.
The minimal subclass looks like this:
import { Think } from "@cloudflare/think";
import { createWorkersAI } from "workers-ai-provider";

export class MyAgent extends Think<Env> {
  getModel() {
    return createWorkersAI({ binding: this.env.AI })(
      "@cf/moonshotai/kimi-k2.5"
    );
  }
}
That’s effectively all you need to have a working chat agent with streaming, persistence, abort/cancel, error handling, resumable streams, and a built-in workspace filesystem. Deploy with npx wrangler deploy.
Think makes decisions for you. When you need more control, you can override the ones you care about:
Override
Purpose
getModel()
Return the LanguageModel to use
getSystemPrompt()
System prompt
getTools()
AI SDK compatible ToolSet for the agentic loop
maxSteps
Max tool-call rounds per turn
configureSession()
Context blocks, compaction, search, skills
Under the hood, Think runs the complete agentic loop on every turn: it assembles the context (base instructions + tool descriptions + skills + memory + conversation history), calls streamText, executes tool calls (with output truncation to prevent context blowup), appends results, loops until the model is done or the step limit is reached. All messages are persisted after each turn.
Lifecycle hooks
Think gives you hooks at every stage of the chat turn, without requiring you to own the whole pipeline:
Switch to a lower cost model for follow-up turns, limit the tools it can use, and pass in client-side context on each turn. Also log every tool call to analytics and automatically trigger one more follow-up turn after the model completes, all without replacing onChatMessage.
Persistent memory and long conversations
Think builds on Session API as its storage layer, giving you tree-structured messages with branching built in.
On top of that, it adds persistent memory through context blocks. These are structured sections of the system prompt that the model can read and update over time, and they persist across hibernation.The model sees “MEMORY (Important facts, use set_context to update) [42%, 462/1100 tokens]” and can proactively remember things.
Sessions are flexible. You can run multiple conversations per agent and fork them to try a different direction without losing the original.
As context grows, Think handles limits with non-destructive compaction. Older messages are summarized instead of removed, while the full history remains stored in SQLite.
Search is built in as well. Using FTS5, you can query conversation history within a session or across all the sessions. The agent is also able to search its own past usingsearch_context tool.
The full execution ladder, wired in
Think integrates the entire execution ladder into a single getTools() return:
Think takes code execution one step further. An agent can write its own extensions: TypeScript programs that run in Dynamic Workers, declaring permissions for network access and workspace operations.
Think’s ExtensionManager bundles the extension (optionally with npm deps via @cloudflare/worker-bundler), loads it into a Dynamic Worker, and registers the new tools. The extension persists in DO storage and survives hibernation. The next time the user asks about pull requests, the agent has a github_create_pr tool that didn’t exist 30 seconds ago.
This is the kind of self-improvement loop that makes agents genuinely more useful over time. Not through fine-tuning or RLHF, but through code. The agent is able to write new capabilities for itself, all in sandboxed, auditable, and revocable TypeScript.
Sub-agent RPC
Think also works as a sub-agent, called via chat() over RPC from a parent, with streaming events via callback:
Each child gets its own conversation tree, memory, tools, and model. The parent doesn’t need to know the details.
Getting started
Project Think is experimental. The API surface is stable but will continue to evolve in the coming days and weeks. We’re already using it internally to build our own background agent infrastructure, and we’re sharing it early so you can build alongside us.
npm install @cloudflare/think agents ai @cloudflare/shell zod workers-ai-provider
// src/client.tsx
import { useAgent } from "agents/react";
import { useAgentChat } from "@cloudflare/ai-chat/react";

function Chat() {
  const agent = useAgent({ agent: "MyAgent" });
  const { messages, sendMessage, status } = useAgentChat({ agent });
  // Render your chat UI
}
Think speaks the same WebSocket protocol as @cloudflare/ai-chat, so existing UI components work out of the box. If you’ve built on AIChatAgent, your client code doesn’t change.
The third wave
We see three waves of AI agents:
The first wave was chatbots. They were stateless, reactive, and fragile. Every conversation started from scratch with no memory, no tools, and no ability to act. This made them useful for answering questions, but limited them to only answering questions.
The second wave was coding agents. These are stateful, tool-using and far more capable tools like Pi, Claude Code, OpenClaw, and Codex. These agents can read codebases, write code, execute it, and iterate. These proved that an LLM with the right tools is a general-purpose machine, but they run on your laptop, for one user, with no durability guarantees.
Now we are entering the third wave: agents as infrastructure. Durable, distributed, structurally safe, and serverless. These are agents that run on the Internet, survive failures, cost nothing when idle, and enforce security through architecture rather than behavior. Agents that any developer can build and deploy for any number of users.
This is the direction we’re betting on.
The Agents SDK is already powering thousands of production agents. With Project Think and the the primitives it introduces, we’re adding the missing pieces to make those agents dramatically more capable: persistent workspaces, sandboxed code execution, durable long-running tasks, structural security, sub-agent coordination, and self-authored extensions.
It’s available today in preview. We’re building alongside you, and we’d genuinely love to see what you (and your coding agent) create with it.
Think is part of the Cloudflare Agents SDK, available as @cloudflare/think. The features described in this post are in preview. APIs may change as we incorporate feedback. Check the documentation and example to get started.
A few weeks ago, we announced Dynamic Workers, a new feature of the Workers platform which lets you load Worker code on-the-fly into a secure sandbox. The Dynamic Worker Loader API essentially provides direct access to the basic compute isolation primitive that Workers has been based on all along: isolates, not containers. Isolates are much lighter-weight than containers, and as such, can load 100x faster using 1/10 the memory. They are so efficient, they can be treated as “disposable”: start one up to run a few lines of code, then throw it away. Like a secure version of eval().
Dynamic Workers have many uses. In the original announcement, we focused on how to use them to run AI-agent-generated code as an alternative to tool calls. In this use case, an AI agent performs actions at the request of a user by writing a few lines of code and executing them. The code is single-use, intended to perform one task one time, and is thrown away immediately after it executes.
But what if you want an AI to generate more persistent code? What if you want your AI to build a small application with a custom UI the user can interact with? What if you want that application to have long-lived state? But of course, you still want it to run in a secure sandbox.
One way to do this would be to use Dynamic Workers, and simply provide the Worker with an RPC API that gives it access to storage. Using bindings, you could give the Dynamic Worker an API that points back to your remote SQL database (perhaps backed by Cloudflare D1, or a Postgres database you access through Hyperdrive — it’s up to you).
But Workers also has a unique and extremely fast type of storage that may be a perfect fit for this use case: Durable Objects. A Durable Object is a special kind of Worker that has a unique name, with one instance globally per name. That instance has a SQLite database attached, which lives on local disk on the machine where the Durable Object runs. This makes storage access ridiculously fast: there is effectively zero latency.
Perhaps, then, what you really want is for your AI to write code for a Durable Object, and then you want to run that code in a Dynamic Worker.
But how?
This presents a weird problem. Normally, to use Durable Objects you have to:
Write a class extending DurableObject.
Export it from your Worker’s main module.
Specify in your Wrangler config that storage should be provision for this class. This creates a Durable Object namespace that points at your class for handling incoming requests.
This doesn’t extend naturally to Dynamic Workers. First, there is the obvious problem: The code is dynamic. You run it without invoking the Cloudflare API at all. But Durable Object storage has to be provisioned through the API, and the namespace has to point at an implementing class. It can’t point at your Dynamic Worker.
But there is a deeper problem: Even if you could somehow configure a Durable Object namespace to point directly at a Dynamic Worker, would you want to? Do you want your agent (or user) to be able to create a whole namespace full of Durable Objects? To use unlimited storage spread around the world?
You probably don’t. You probably want some control. You may want to limit, or at least track, how many objects they create. Maybe you want to limit them to just one object (probably good enough for vibe-coded personal apps). You may want to add logging and other observability. Metrics. Billing. Etc.
To do all this, what you really want is for requests to these Durable Objects to go to your code first, where you can then do all the “logistics”, and then forward the request into the agent’s code. You want to write a supervisor that runs as part of every Durable Object.
Solution: Durable Object Facets
Today we are releasing, in open beta, a feature that solves this problem.
Durable Object Facets allow you to load and instantiate a Durable Object class dynamically, while providing it with a SQLite database to use for storage. With Facets:
First you create a normal Durable Object namespace, pointing to a class you write.
In that class, you load the agent’s code as a Dynamic Worker, and call into it.
The Dynamic Worker’s code can implement a Durable Object class directly. That is, it literally exports a class declared as extends DurableObject.
You are instantiating that class as a “facet” of your own Durable Object.
The facet gets its own SQLite database, which it can use via the normal Durable Object storage APIs. This database is separate from the supervisor’s database, but the two are stored together as part of the same overall Durable Object.
How it works
Here is a simple, complete implementation of an app platform that dynamically loads and runs a Durable Object class:
import { DurableObject } from "cloudflare:workers";

// For the purpose of this example, we'll use this static
// application code, but in the real world this might be generated
// by AI (or even, perhaps, a human user).
const AGENT_CODE = `
  import { DurableObject } from "cloudflare:workers";

  // Simple app that remembers how many times it has been invoked
  // and returns it.
  export class App extends DurableObject {
    fetch(request) {
      // We use storage.kv here for simplicity, but storage.sql is
      // also available. Both are backed by SQLite.
      let counter = this.ctx.storage.kv.get("counter") || 0;
      ++counter;
      this.ctx.storage.kv.put("counter", counter);

      return new Response("You've made " + counter + " requests.\\n");
    }
  }
`;

// AppRunner is a Durable Object you write that is responsible for
// dynamically loading applications and delivering requests to them.
// Each instance of AppRunner contains a different app.
export class AppRunner extends DurableObject {
  async fetch(request) {
    // We've received an HTTP request, which we want to forward into
    // the app.

    // The app itself runs as a child facet named "app". One Durable
    // Object can have any number of facets (subject to storage limits)
    // with different names, but in this case we have only one. Call
    // this.ctx.facets.get() to get a stub pointing to it.
    let facet = this.ctx.facets.get("app", async () => {
      // If this callback is called, it means the facet hasn't
      // started yet (or has hibernated). In this callback, we can
      // tell the system what code we want it to load.

      // Load the Dynamic Worker.
      let worker = this.#loadDynamicWorker();

      // Get the exported class we're interested in.
      let appClass = worker.getDurableObjectClass("App");

      return { class: appClass };
    });

    // Forward request to the facet.
    // (Alternatively, you could call RPC methods here.)
    return await facet.fetch(request);
  }

  // RPC method that a client can call to set the dynamic code
  // for this app.
  setCode(code) {
    // Store the code in the AppRunner's SQLite storage.
    // Each unique code must have a unique ID to pass to the
    // Dynamic Worker Loader API, so we generate one randomly.
    this.ctx.storage.kv.put("codeId", crypto.randomUUID());
    this.ctx.storage.kv.put("code", code);
  }

  #loadDynamicWorker() {
    // Use the Dynamic Worker Loader API like normal. Use get()
    // rather than load() since we may load the same Worker many
    // times.
    let codeId = this.ctx.storage.kv.get("codeId");
    return this.env.LOADER.get(codeId, async () => {
      // This Worker hasn't been loaded yet. Load its code from
      // our own storage.
      let code = this.ctx.storage.kv.get("code");

      return {
        compatibilityDate: "2026-04-01",
        mainModule: "worker.js",
        modules: { "worker.js": code },
        globalOutbound: null,  // block network access
      }
    });
  }
}

// This is a simple Workers HTTP handler that uses AppRunner.
export default {
  async fetch(req, env, ctx) {
    // Get the instance of AppRunner named "my-app".
    // (Each name has exactly one Durable Object instance in the
    // world.)
    let obj = ctx.exports.AppRunner.getByName("my-app");

    // Initialize it with code. (In a real use case, you'd only
    // want to call this once, not on every request.)
    await obj.setCode(AGENT_CODE);

    // Forward the request to it.
    return await obj.fetch(req);
  }
}
In this example:
AppRunner is a “normal” Durable Object written by the platform developer (you).
Each instance of AppRunner manages one application. It stores the app code and loads it on demand.
The application itself implements and exports a Durable Object class, which the platform expects is named App.
AppRunner loads the application code using Dynamic Workers, and then executes the code as a Durable Object Facet.
Each instance of AppRunner is one Durable Object composed of two SQLite databases: one belonging to the parent (AppRunner itself) and one belonging to the facet (App). These databases are isolated: the application cannot read AppRunner‘s database, only its own.
To run the example, copy the code above into a file worker.js, pair it with the following wrangler.jsonc, and run it locally with npx wrangler dev.
Matrix is the gold standard for decentralized, end-to-end encrypted communication. It powers government messaging systems, open-source communities, and privacy-focused organizations worldwide.
For the individual developer, however, the appeal is often closer to home: bridging fragmented chat networks (like Discord and Slack) into a single inbox, or simply ensuring your conversation history lives on infrastructure you control. Functionally, Matrix operates as a decentralized, eventually consistent state machine. Instead of a central server pushing updates, homeservers exchange signed JSON events over HTTP, using a conflict resolution algorithm to merge these streams into a unified view of the room’s history.
But there is a “tax” to running it Traditionally, operating a Matrix homeserver has meant accepting a heavy operational burden. You aren’t just installing software; you are becoming a system administrator. You have to provision virtual private servers (VPS), tune PostgreSQL for heavy write loads, manage Redis for caching, configure reverse proxies, and handle rotation for TLS certificates. It’s a stateful, heavy beast that demands to be fed time and money, whether you are sending one message a day or one million.
We wanted to see if we could eliminate that tax entirely.
Spoiler: We could. In this post, we’ll explain how we ported a complete Matrix homeserver to Cloudflare Workers. The result is a serverless architecture where operations disappear, costs scale to zero when idle, and every connection is protected by post-quantum cryptography by default. You can view the source code and deploy your own instance directly from GitHub.
From Tuwunel to Workers
Our starting point was Tuwunel, a Rust-based Matrix homeserver designed for traditional deployments. PostgreSQL for persistence, Redis for caching, filesystem for media. Porting it to Workers meant questioning every storage assumption we’d taken for granted.
The good news: Rust compiles to WebAssembly, and the core Matrix protocol logic — event authorization, room state resolution, cryptographic verification — translated directly. The workers-rs crate bridges the gap to Cloudflare’s runtime.
The challenge was storage. Traditional homeservers assume strong consistency via a central SQL database. Cloudflare offers a powerful alternative: Durable Objects. This primitive gives us the strong consistency and atomicity required for Matrix state resolution, while still allowing the application to run at the edge.
Here’s how the mapping worked out:
From monolith to serverless
Moving to Cloudflare Workers brings several advantages for a developer: simple deployment, lower costs, low latency, and built-in security.
Easy deployment: A traditional Matrix deployment requires server provisioning, PostgreSQL administration, Redis cluster management, TLS certificate renewal, load balancer configuration, monitoring infrastructure, and on-call rotations.
With Workers, deployment is wrangler deploy. We handle TLS, load balancing, DDoS protection, and global distribution. So there’s no server to patch, no database to vacuum, or certificates to renew.
Usage-based costs: Traditional homeservers cost money whether anyone is using them or not. A small community server handling a few hundred requests per day still requires a typical VPS costing around $20/month running 24/7.
Workers pricing is request-based, so low-traffic homeservers cost just pennies. When usage spikes during active conversations, you pay for what you use. When everyone goes to sleep, costs drop toward zero.
Lower latency globally: A traditional Matrix homeserver in us-east-1 adds 200ms+ latency for users in Asia or Europe. Every sync request, message sent, and typing indicator go round-trip to a single region.
Workers, meanwhile, run in 300+ locations worldwide. When a user in Tokyo sends a message, the Worker executes in Tokyo.
Built-in security: Matrix homeservers can be high-value targets: They handle encrypted communications, store message history, and authenticate users. Traditional deployments require careful hardening: firewall configuration, rate limiting, DDoS mitigation, WAF rules, IP reputation filtering.
We provide all of this by default. The Worker never sees attack traffic, because we filter it first. For a solo developer or small team, achieving this level of hardening on a Linux VPS is a full-time job. On Workers, it is the baseline environment.
An adversary captures your encrypted TLS traffic today and stores it. Years from now, when quantum computers can break classical key exchange algorithms, they decrypt everything retroactively. For a messaging platform handling sensitive communications, this isn’t theoretical. Government agencies and well-funded adversaries are already stockpiling encrypted traffic.
Fortunately, we didn’t have to protect against this by ourselves. Cloudflare deployed post-quantum hybrid key agreement across all TLS 1.3 connections in October 2022. Every connection to our Worker automatically negotiates X25519MLKEM768 — a hybrid combining classical X25519 with ML-KEM, the post-quantum algorithm standardized by NIST.
Classical cryptography relies on mathematical problems that are hard for traditional computers but trivial for quantum computers running Shor’s algorithm. ML-KEM is based on lattice problems that remain hard even for quantum computers. The hybrid approach means both algorithms must fail for the connection to be compromised.
Following a message through the system
Understanding where encryption happens matters for security architecture. When someone sends a message through our homeserver, here’s the actual path:
The sender’s client takes the plaintext message and encrypts it with Megolm — Matrix’s end-to-end encryption. This encrypted payload then gets wrapped in TLS for transport. On Cloudflare, that TLS connection uses X25519MLKEM768, making it quantum-resistant.
The Worker terminates TLS, but what it receives is still encrypted — the Megolm ciphertext. We store that ciphertext in D1, index it by room and timestamp, and deliver it to recipients. But we never see the plaintext. The message “Hello, world” exists only on the sender’s device and the recipient’s device.
When the recipient syncs, the process reverses. They receive the encrypted payload over another quantum-resistant TLS connection, then decrypt locally with their Megolm session keys.
Two layers, independent protection
This creates defense in depth through two encryption layers that operate independently:
The transport layer (TLS) protects data in transit. It’s encrypted at the client and decrypted at the Cloudflare edge. With X25519MLKEM768, this layer is now post-quantum.
The application layer (Megolm E2EE) protects message content. It’s encrypted on the sender’s device and decrypted only on recipient devices. This uses classical Curve25519 cryptography.
Here’s why this architecture matters: Even if Matrix E2EE is eventually broken by quantum computers, the message content was never transmitted in a quantum-vulnerable form. The TLS layer that carried the E2EE ciphertext was itself post-quantum secured.
The post-quantum TLS acts as a quantum-resistant envelope around everything, including the classical E2EE layer. This buys time for the Matrix protocol to migrate to post-quantum E2EE algorithms without leaving current communications vulnerable to harvest-now-decrypt-later attacks.
Who sees what
Any Matrix homeserver operator — whether running Synapse on a VPS or this implementation on Workers — can see metadata: which rooms exist, who’s in them, when messages were sent. This is inherent to operating the server. You’re the operator; you control the infrastructure.
What no one in the infrastructure chain can see: message content. The E2EE payload is encrypted on sender devices before it ever hits the network. Cloudflare terminates TLS and passes requests to your Worker, but both see only Megolm ciphertext. Media in encrypted rooms is encrypted client-side before upload. Private keys never leave user devices.
The server processes ciphertext, not conversations. That’s true whether you’re self-hosting on bare metal or running on Workers.
What traditional deployments would need
Achieving post-quantum TLS on a traditional Matrix deployment would require upgrading OpenSSL or BoringSSL to a version supporting ML-KEM, configuring cipher suite preferences correctly, testing client compatibility across all Matrix apps, monitoring for TLS negotiation failures, staying current as PQC standards evolve, and handling clients that don’t support PQC gracefully.
With Workers, it’s automatic. Chrome, Firefox, and Edge all support X25519MLKEM768. Mobile apps using platform TLS stacks inherit this support. The security posture improves as Cloudflare’s PQC deployment expands — no action required on our part.
The storage architecture that made it work
The key insight from porting Tuwunel was that different data needs different consistency guarantees. We use each Cloudflare primitive for what it does best.
D1 for the data model
D1 stores everything that needs to survive restarts and support queries: users, rooms, events, device keys. Over 25 tables covering the full Matrix data model.
CREATE TABLE events (
	event_id TEXT PRIMARY KEY,
	room_id TEXT NOT NULL,
	sender TEXT NOT NULL,
	event_type TEXT NOT NULL,
	state_key TEXT,
	content TEXT NOT NULL,
	origin_server_ts INTEGER NOT NULL,
	depth INTEGER NOT NULL
);
D1’s SQLite foundation meant we could port Tuwunel’s queries with minimal changes. Joins, indexes, and aggregations work as expected.
We learned one hard lesson: D1’s eventual consistency breaks foreign key constraints. A write to rooms might not be visible when a subsequent write to events checks the foreign key — different replicas, different views of the world. We removed all foreign keys and enforce referential integrity in application code.
KV for ephemeral state
OAuth authorization codes live for 10 minutes. Refresh tokens last for a session. None of this needs SQL — it needs fast key-value access with automatic expiration.
// Store OAuth code with 10-minute TTL
kv.put(&format!("oauth_code:{}", code), &token_data)?
	.expiration_ttl(600)
	.execute()
	.await?;
KV’s global distribution means OAuth flows work fast regardless of where users are located.
R2 for media
Matrix media maps directly to R2. Upload an image, get back a content-addressed URL. Egress is free, which matters for a protocol where clients frequently download the same avatars and images.
Durable Objects for atomicity
Some operations can’t tolerate eventual consistency. When a client claims a one-time encryption key, that key must be atomically removed. If two clients claim the same key, encrypted session establishment fails.
Durable Objects provide single-threaded, strongly consistent storage:
#[durable_object]
pub struct UserKeysObject {
	state: State,
	env: Env,
}

impl UserKeysObject {
	async fn claim_otk(&self, algorithm: &str) -> Result<Option<Key>> {
    	// Atomic within single DO - no race conditions possible
    	let mut keys: Vec<Key> = self.state.storage()
        	.get("one_time_keys")
        	.await
        	.ok()
        	.flatten()
        	.unwrap_or_default();

    	if let Some(idx) = keys.iter().position(|k| k.algorithm == algorithm) {
        	let key = keys.remove(idx);
        	self.state.storage().put("one_time_keys", &keys).await?;
        	return Ok(Some(key));
    	}
    	Ok(None)
	}
}
We use UserKeysObject for E2EE key management, RoomObject for real-time room events like typing indicators and read receipts, and UserSyncObject for to-device message queues. The rest flows through D1.
Complete E2EE, complete OAuth
End-to-end encryption is non-negotiable for secure communications. Our implementation supports the full Matrix E2EE stack: device keys, cross-signing keys, one-time keys, fallback keys, key backup, and dehydrated devices.
Modern Matrix clients use OAuth 2.0/OIDC instead of legacy password flows. We implemented a complete OAuth provider: dynamic client registration, PKCE authorization, RS256-signed JWT tokens, token refresh with rotation, and standard OIDC discovery endpoints.
Point Element or any Matrix client at the domain, and it discovers everything automatically.
Sliding Sync for mobile
Traditional Matrix sync transfers megabytes of data on initial connection — every room, every state event, recent timeline for each. This destroys mobile battery and data plans.
Sliding Sync lets clients request exactly what they need. Instead of downloading everything, clients get the 20 most recent rooms with minimal state. As users scroll, they request more ranges. The server tracks position and sends only deltas.
Combined with edge execution, mobile clients can connect and render their room list in under 500ms — even on slow networks.
The comparison
For a homeserver serving a small team:
Traditional (VPS)
Workers
Monthly cost (idle)
$20-50
<$1
Monthly cost (active)
$20-50
$3-10
Global latency
100-300ms
20-50ms
Time to deploy
Hours
Seconds
Maintenance
Weekly
None
DDoS protection
Additional cost
Included
Post-quantum TLS
Complex setup
Automatic
*Based on public rates and metrics published by DigitalOcean, AWS Lightsail, and Linode as of January 15, 2026.
The economics improve further at scale. Traditional deployments require capacity planning and over-provisioning. Workers scale automatically.
The future of decentralized protocols
When we started this project, the goal was simply to see if the pieces would fit. Could a protocol as complex and stateful as Matrix — designed for heavy iron and persistent file systems — actually run on an ephemeral, serverless edge?
The answer is yes, but the implication is bigger than just Matrix.
By mapping traditional stateful components to Cloudflare’s primitives — Postgres to D1, Redis to KV, mutexes to Durable Objects — we proved that complex applications don’t need complex infrastructure. We stripped away the operating system, the database management, and the network configuration, leaving only the application logic and the data itself.
This architecture shifts the paradigm for self-hosting. It turns “running a server” from a chore into a utility. You get the sovereignty of owning your data without the burden of owning the infrastructure.
Matrix on Workers runs in production today, handling real encrypted communications for our team. It is fast, it is cheap, and it is arguably one of the most secure ways to deploy a homeserver today.
Ready to build secure, real-time applications on Workers? Get started withCloudflare Workers and exploreDurable Objects for your own stateful edge applications. Join ourDiscord community to connect with other developers building at the edge.
Social media users are tired of losing their identity and data every time a platform shuts down or pivots. In the ATProto ecosystem — short for Authenticated Transfer Protocol — users own their data and identities. Everything they publish becomes part of a global, cryptographically signed shared social web. Bluesky is the first big example, but a new wave of decentralized social networks is just beginning. In this post I’ll show you how to get started, by building and deploying a fully serverless ATProto application on Cloudflare’s Developer Platform.
Why serverless? The overhead of managing VMs, scaling databases, maintaining CI pipelines, distributing data across availability zones, and securing APIs against DDoS attacks pulls focus away from actually building.
That’s where Cloudflare comes in. You can take advantage of our Developer Platform to build applications that run on our global network: Workers deploy code globally in milliseconds, KV provides fast, globally distributed caching, D1 offers a distributed relational database, and Durable Objects manage WebSockets and handle real-time coordination. Best of all, everything you need to build your serverless ATProto application is available on our free tier, so you can get started without spending a cent.
The ATProto ecosystem: a quick introduction
Let’s start with a conceptual overview of how data flows in the ATProto ecosystem:
Users interact with apps, which write updates to their personal repositories. Those updates trigger change events, which are published to a relay and broadcast through the global event stream. Any app can subscribe to these events — even if it didn’t publish the original update — because in ATProto, repos, relays, and apps are all independent components, which can be (and are) run by different operators.
Identity
User identity starts with handles — human-readable names like alice.example.com. Each handle must be a valid domain name, allowing the protocol to leverage DNS to provide a global view of who owns what account. Handles map to a user’s Decentralized Identifier (DID), which contains the location of the user’s Personal Data Server (PDS).
Authentication
A user’s PDS manages their keys and repos. It handles authentication and provides an authoritative view of their data via their repo.
What’s different here — and easy to miss — is how little any part of this stack relies on trust in a single service. DID resolution is verifiable. The PDS is user-selected. The client app is just an interface.
When we publish or fetch data, it’s signed and self-validating. That means any other app can consume or build on top of it without asking permission, and without trusting our backend.
Our application
We’ll be working with Statusphere, a tiny but complete demo app built by the ATProto team. It’s the simplest possible social media app: users post single-emoji status updates. Because it’s so minimal, Statusphere is a perfect starting point for learning how decentralized ATProto apps work, and how to adapt them to run on Cloudflare’s serverless stack.
Statusphere schema
In ATProto, all repository data is typed using Lexicons — a shared schema language similar to JSON-Schema. For Statusphere, we use the xyz.statusphere.status record, originally defined by the ATProto team:
Lexicons are strongly typed, which allows for easy interoperability between apps.
How it’s built
In this section, we’ll follow the flow of data inside Statusphere: from authentication, to repo reads and writes, to real-time updates, and look at how we handle live event streams on serverless infrastructure.
1. Language choice
ATProto’s core libraries are written in TypeScript, and Cloudflare Workers provide first-class TypeScript support. It’s the natural starting point for building ATProto services on Cloudflare Workers.
Cloudflare also supports Rust in Workers via WASM cross-compilation, so I tried that next. The ATProto Rust crates and codegen tooling make strong use of Rust’s type system and build tooling, but they’re still in active development. Rust’s WASM ecosystem is solid, though, so I was able to get a working prototype running quickly by adapting an existing Rust implementation of Statusphere — originally written by Bailey Townsend. You can find the code in this GitHub repo.
If you’re building ATProto apps on Cloudflare Workers, I’d suggest contributing to the TypeScript libraries to better support serverless runtimes. A TypeScript version of this app would be a great next step — if you’re interested in building it, please get in touch via the Cloudflare Developer Discord server.
2. Follow along
Use this Deploy to Cloudflare button to clone the repo and set up your own KV and D1 instances and a CI pipeline.
Follow the steps at this link, use the default values or choose custom names, and it’ll build and deploy your own Statusphere Worker.
Note: this project includes a scheduled component that reads from the public event stream. You may wish to delete it when you finish experimenting to save resources.
3. Resolving the user’s handle
To interact with a user’s data, we start by resolving their handle to a DID using the record registered at the _atproto subdomain. For example, my handle is inanna.recursion.wtf, so my DID record is stored at _atproto.inanna.recursion.wtf. The value of that record is did:plc:p2sm7vlwgcbbdjpfy6qajd4g.
We then resolve the DID to its corresponding DID Document, which contains identity metadata including the location of the user’s Personal Data Server. Depending on the DID method, this resolution is handled directly via DNS (for did:web identifiers) or, more frequently, via the Public Ledger of Credentials for did:plc identifiers.
Since these values don’t change frequently, we cache them using Cloudflare KV — it’s perfect for cases like this, where we have some infrequently updated but frequently read key-value mapping that needs to be globally available with low latency.
From the DID document, we extract the location of the user’s Personal Data Server. In my case, it’s bsky.social, but other users may self-host their own PDS or use an alternative provider.
The details of the OAuth flow aren’t important here — you can read the code I used to implement it or dig into the OAuth spec if you’re curious — but the short version is: the user signs in via their PDS, and it grants our app permission to act on their behalf, using the signing keys it manages.
We persist session data in a secure session cookie using tower-sessions. This means that only an opaque session ID is stored client-side, and all session/oauth state data is stored in Cloudflare KV. Again, it’s a natural fit for this use case.
When a user posts a new emoji status, we create a new record in their personal repo — using the same authenticated agent we used to fetch their data. This time, instead of reading, we perform a create record operation:
let uri = agent.create_status(form.status.clone()).await?.uri;
The operation returns a URI — the canonical identifier for the new record.
We then write the status update into D1, so it can immediately be reflected in the UI.
6. Using Durable Objects to broadcast updates
Every active homepage maintains a WebSocket connection to a Durable Object, which acts as a lightweight real-time message broker. When idle, the Durable Object hibernates, saving resources while keeping the WebSocket connections alive. We send a message to the Durable Object to wake it up and broadcast the new update:
for ws in self.state.get_websockets() {
    ws.send(&status);
}
It then iterates over every live WebSocket and sends the update.
One practical note: Durable Objects perform better when sharded across instances. For simplicity, I’ve described the case where everything runs everything through one single Durable Object.
To scale beyond that, the next step would be using multiple Durable Object instances per supported location using location hints, to minimize latency for users around the globe and avoid bottlenecks if we encounter high numbers of concurrent users in a single location. I initially considered implementing this pattern, but it conflicted with my goal of creating a concise ‘hello world’ style example that ATProto devs could clone and use as a template for their app.
7. Listening for live changes
The challenge: realtime feeds vs serverless
Publishing updates inside our own app is easy, but in the ATProto ecosystem, other applications can publish status updates for users. If we want Statusphere to be fully integrated, we need to pick up those events too.
Listening for live event updates requires a persistent WebSocket connection to the ATProto Jetstream service. Traditional server-based apps can keep WebSocket client sockets open indefinitely, but serverless platformscan’t — workers aren’t allowed to run forever.
We need a way to “listen” without running a live server.
The solution: Cloudflare worker Cron Triggers
To solve this, we moved the listening logic into a Cron Trigger — instead of keeping a live socket open, we used this feature to read updates in small batches using a recurring scheduled job.
When the scheduled worker invocation fires, it loads the last seen cursor from its persistent storage. Then it connects to Jetstream — a streaming service for ATProto repo events — filtered by the xyz.statusphere.status collection and starting at the last seen cursor.
let ws = WebSocket::connect("wss://jetstream1.us-east.bsky.network/subscribe?wantedCollections=xyz.statusphere.status&cursor={cursor}").await?;
We store a cursor — a microsecond timestamp marking the last message we received — in the Durable Object’s persistent storage, so even if the object restarts, it knows exactly where to resume. As soon as we process an event newer than our start time, we close the WebSocket connection and let the Durable Object go back to sleep.
The tradeoff: updates can lag by up to a minute, but the system stays fully serverless. This is a great fit for early-stage apps and prototypes, where minimizing infrastructure complexity matters more than achieving perfect real-time delivery.
Optional upgrade: real-time event listener
If you want real time updates, and you’re willing to bend the serverless model slightly, you can deploy a lightweight listener process that maintains a live WebSocket connection to Jetstream.
Instead of polling once a minute, this process listens for new events for the xyz.statusphere.status collection and pushes updates to our Cloudflare Worker as soon as they arrive. When this mode is active, we disable the Cron Trigger step with an environment variable. You can find a sketch of this listener process here and the endpoint that handles updates from it here.
The result still isn’t a traditional server:
No public exposure to the web
No open HTTP ports
No persistent database
It’s just a single-purpose, stateless listener — something simple enough to run on a home server until your app grows large enough to need more serious infrastructure.
Later on, you could swap this design for something more scalable using tools like Cloudflare Queues to provide batching and retries — but for small-to-medium apps, this lightweight listener is an easy and effective upgrade.
Looking ahead
Today, Durable Objects can hibernate while holding long-lived WebSocket server connections but don’t support hibernation when holding long-lived WebSocket client connections (like a Jetstream listener). That’s why Statusphere uses workarounds — scheduled Worker invocations via Cron Trigger and lightweight external listeners — to stay synced with the network.
Future improvements to Durable Objects — like adding support for hibernating active WebSocket clients — could remove the need for these workarounds entirely.
Build your own ATProto app
This is a full-featured atproto app running entirely on Cloudflare with zero servers and minimal ops overhead. Workers run your code within 50 ms of most users, KV and D1 keep your data available, and Durable Objects handle WebSocket fan-out and live coordination.
Use the Deploy to Cloudflare Button to clone the repo and set up your serverless environment. Then show us what you build. Drop a link in our Discord, or tag @cloudflare.social on Bluesky or @CloudflareDev on X — we’d love to see it.
There’s a lot of talk right now about building AI agents, but not a lot out there about what it takes to make those agents truly useful.
An Agent is an autonomous system designed to make decisions and perform actions to achieve a specific goal or set of goals, without human input.
No matter how good your agent is at making decisions, you will need a person to provide guidance or input on the agent’s path towards its goal. After all, an agent that cannot interact or respond to the outside world and the systems that govern it will be limited in the problems it can solve.
That’s where the “human-in-the-loop” interaction pattern comes in. You’re bringing a human into the agent’s loop and requiring an input from that human before the agent can continue on its task.
In this blog post, we’ll useKnock and the CloudflareAgents SDK to build an AI Agent for a virtual card issuing workflow that requires human approval when a new card is requested.
Knock is messaging infrastructure you can use to send multi-channel messages across in-app, email, SMS, push, and Slack, without writing any integration code.
With Knock, you gain complete visibility into the messages being sent to your users while also handling reliable delivery, user notification preferences, and more.
You can use Knock to power human-in-the-loop flows for your agents using Knock’sAgent Toolkit, which is a set of tools that expose Knock’s APIs and messaging capabilities to your AI agents.
Using the Agent SDK as the foundation of our AI Agent
The Agents SDK provides an abstraction for building stateful, real-time agents on top of Durable Objects that are globally addressable and persist state using an embedded, zero-latency SQLite database.
Building an AI agent outside of using the Agents SDK and the Cloudflare platform means we need to consider WebSocket servers, state persistence, and how to scale our service horizontally. Because a Durable Object backs the Agents SDK, we receive these benefits for free, while having a globally addressable piece of compute with built-in storage, that’s completely serverless and scales to zero.
In the example, we’ll use these features to build an agent that users interact with in real-time via chat, and that can be paused and resumed as needed. The Agents SDK is the ideal platform for powering asynchronous agentic workflows, such as those required in human-in-the-loop interactions.
Setting up our Knock messaging workflow
Within Knock, we design our approval workflow using the visual workflow builder to create the cross-channel messaging logic. We then make the notification templates associated with each channel to which we want to send messages.
Knock will automatically apply theuser’s preferences as part of the workflow execution, ensuring that your user’s notification settings are respected.
You can find an example workflow that we’ve already created for this demo in the repository. You can use this workflow template via theKnock CLI to import it into your account.
Building our chat UI
We’ve built the AI Agent as a chat interface on top of the AIChatAgent abstraction from Cloudflare’s Agents SDK (docs). The Agents SDK here takes care of the bulk of the complexity, and we’re left to implement our LLM calling code with our system prompt.
// src/index.ts

import { AIChatAgent } from "agents/ai-chat-agent";
import { openai } from "@ai-sdk/openai";
import { createDataStreamResponse, streamText } from "ai";

export class AIAgent extends AIChatAgent {
  async onChatMessage(onFinish) {
    return createDataStreamResponse({
      execute: async (dataStream) => {
        try {
          const stream = streamText({
            model: openai("gpt-4o-mini"),
            system: `You are a helpful assistant for a financial services company. You help customers with credit card issuing.`,
            messages: this.messages,
            onFinish,
            maxSteps: 5,
          });

          stream.mergeIntoDataStream(dataStream);
        } catch (error) {
          console.error(error);
        }
      },
    });
  }
}
On the client side, we’re using the useAgentChat hook from the agents/ai-react package to power the real-time user-to-agent chat.
We’ve modeled our agent as a chat per user, which we set up using the useAgent hook by specifying the name of the process as the userId.
This means we have an agent process, and therefore a durable object, per-user. For our human-in-the-loop use case, this becomes important later on as we talk about resuming our deferred tool call.
Deferring the tool call to Knock
We give the agent our card issuing capability through exposing an issueCard tool. However, instead of writing the approval flow and cross-channel logic ourselves, we delegate it entirely to Knock by wrapping the issue card tool in our requireHumanInput method.
Now when the user asks to request a new card, we make a call out to Knock to initiate our card request, which will notify the appropriate admins in the organization to request an approval.
To set this up, we need to use Knock’s Agent Toolkit, which exposes methods to work with Knock in our AI agent and power cross-channel messaging.
import { createKnockToolkit } from "@knocklabs/agent-toolkit/ai-sdk";
import { tool } from "ai";
import { z } from "zod";

import { AIAgent } from "./index";
import { issueCard } from "./api";
import { BASE_URL } from "./constants";

async function initializeToolkit(agent: AIAgent) {
  const toolkit = await createKnockToolkit({ serviceToken: agent.env.KNOCK_SERVICE_TOKEN });

  const issueCardTool = tool({
    description: "Issue a new credit card to a customer.",
    parameters: z.object({
      customerId: z.string(),
    }),
    execute: async ({ customerId }) => {
      return await issueCard(customerId);
    },
  });

  const { issueCard } = toolkit.requireHumanInput(
    { issueCard: issueCardTool },
    {
      workflow: "approve-issued-card",
      actor: agent.name,
      recipients: ["admin_user_1"],
      metadata: {
        approve_url: `${BASE_URL}/card-issued/approve`,
        reject_url: `${BASE_URL}/card-issued/reject`,
      },
    }
  );

  return { toolkit, tools: { issueCard } };
}
There’s a lot going on here, so let’s walk through the key parts:
We wrap our issueCard tool in the requireHumanInput method, exposed from the Knock Agent Toolkit
We want the messaging workflow to be invoked to be our approve-issued-card workflow
We pass the agent.name as the actor of the request, which translates to the user ID
We set the recipient of this workflow to be the user admin_user_1
We pass the approve and reject URLs so that they can be used in our message templates
The wrapped tool is then returned as issueCard
Under the hood, these options are passed to theKnock workflow trigger API to invoke a workflow per-recipient. The set of the recipients listed here could be dynamic, or go to a group of users throughKnock’s subscriptions API.
We can then pass the wrapped issue card tool to our LLM call in the onChatMessage method on the agent so that the tool call can be called as part of the interaction with the agent.
export class AIAgent extends AIChatAgent {
  // ... other methods

  async onChatMessage(onFinish) {
    const { tools } = await initializeToolkit(this);

    return createDataStreamResponse({
      execute: async (dataStream) => {
        const stream = streamText({
          model: openai("gpt-4o-mini"),
          system: "You are a helpful assistant for a financial services company. You help customers with credit card issuing.",
          messages: this.messages,
          onFinish,
          tools,
          maxSteps: 5,
        });

        stream.mergeIntoDataStream(dataStream);
      },
    });
  }
}
Now when the agent calls the issueCardTool, we invoke Knock to send our approval notifications, deferring the tool call to issue the card until we receive an approval. Knock’s workflows take care of sending out the message to the set of recipient’s specified, generating and delivering messages according to each user’s preferences.
Using Knockworkflows for our approval message makes it easy to build cross-channel messaging to reach the user according to their communicationpreferences. We can also leveragedelays,throttles,batching, andconditions to orchestrate more complex messaging.
Handling the approval
Once the message has been sent to our approvers, the next step is to handle the approval coming back, bringing the human into the agent’s loop.
The approval request is asynchronous, meaning that the response can come at any point in the future. Fortunately, Knock takes care of the heavy lifting here for you, routing the event to the agent worker via awebhook that tracks the interaction with the underlying message. In our case, that’s a click to the “approve” or “reject” button.
First, we set up a message.interacted webhook handler within the Knock dashboard to forward the interactions to our worker, and ultimately to our agent process.
In our example here, we route the approval click back to the worker to handle, appending a Knock message ID to the end of the approve_url and reject_url to track engagement against the specific message sent. We do this via liquid inside of our message templates in Knock: {{ data.approve_url }}?messageId={{ current_message.id }} . One caveat here is that if this were a production application, we’re likely going to handle our approval click in a different application than this agent is running. We co-located it here for the purposes of this demo only.
Once the link is clicked, we have a handler in our worker to mark the message as interacted using Knock’smessage interaction API, passing through the status as metadata so that it can be used later.
import Knock from '@knocklabs/node';
import { Hono } from "hono";

const app = new Hono();
const client = new Knock();

app.get("/card-issued/approve", async (c) => {
  const { messageId } = c.req.query();

  if (!messageId) return c.text("No message ID found", { status: 400 });

  await client.messages.markAsInteracted(messageId, {
    status: "approved",
  });

  return c.text("Approved");
});
The message interaction will flow from Knock to our worker via the webhook we set up, ensuring that the process is fully asynchronous. The payload of the webhook includes the full message, including metadata about the user that generated the original request, and keeps details about the request itself, which in our case contains the tool call.
import { getAgentByName, routeAgentRequest } from "agents";
import { Hono } from "hono";

const app = new Hono();

app.post("/incoming/knock/webhook", async (c) => {
  const body = await c.req.json();
  const env = c.env as Env;

  // Find the user ID from the tool call for the calling user
  const userId = body?.data?.actors[0];

  if (!userId) {
    return c.text("No user ID found", { status: 400 });
  }

  // Find the agent DO for the user
  const existingAgent = await getAgentByName(env.AIAgent, userId);

  if (existingAgent) {
    // Route the request to the agent DO to process
    const result = await existingAgent.handleIncomingWebhook(body);

    return c.json(result);
  } else {
    return c.text("Not found", { status: 404 });
  }
});
We leverage the agent’s ability to be addressed by a named identifier to route the request from the worker to the agent. In our case, that’s the userId. Because the agent is backed by a durable object, this process of going from incoming worker request to finding and resuming the agent is trivial.
Resuming the deferred tool call
We then use the context about the original tool call, passed through to Knock and round tripped back to the agent, to resume the tool execution and issue the card.
export class AIAgent extends AIChatAgent {
  // ... other methods

  async handleIncomingWebhook(body: any) {
    const { toolkit } = await initializeToolkit(this);

    const deferredToolCall = toolkit.handleMessageInteraction(body);

    if (!deferredToolCall) {
      return { error: "No deferred tool call given" };
    }

    // If we received an "approved" status then we know the call was approved
    // so we can resume the deferred tool call execution
    if (result.interaction.status === "approved") {
      const toolCallResult =
	      await toolkit.resumeToolExecution(result.toolCall);

      const { response } = await generateText({
        model: openai("gpt-4o-mini"),
        prompt: `You were asked to issue a card for a customer. The card is now approved. The result was: ${JSON.stringify(toolCallResult)}.`,
      });

      const message = responseToAssistantMessage(
        response.messages[0],
        result.toolCall,
        toolCallResult
      );

      // Save the message so that it's displayed to the user
      this.persistMessages([...this.messages, message]);
    }

    return { status: "success" };
  }
}
Again, there’s a lot going on here, so let’s step through the important parts:
We attempt to transform the body, which is the webhook payload from Knock, into a deferred tool call via the handleMessageInteraction method
If the metadata status we passed through to the interaction call earlier has an “approved” status then we resume the tool call via the resumeToolExecution method
Finally, we generate a message from the LLM and persist it, ensuring that the user is informed of the approved card
With this last piece in place, we can now request a new card be issued, have an approval request be dispatched from the agent, send the approval messages, and route those approvals back to our agent to be processed. The agent will asynchronously process our card issue request and the deferred tool call will be resumed for us, with very little code.
Protecting against duplicate approvals
One issue with the above implementation is that we’re prone to issuing multiple cards if someone clicks on the approve button more than once. To rectify this, we want to keep track of the tool calls being issued, and ensure that the call is processed at most once.
To power this we leverage theagent’s built-in state, which can be used to persist information without reaching for another persistence store like a database or Redis, although we could absolutely do so if we wished. We can track the tool calls by their ID and capture their current status, right inside the agent process.
Here, we create the initial state for the tool calls as an empty object. We also add a quick setter helper method to make interactions easier.
Next up, we need to record the tool call being made. To do so, we can use the onAfterCallKnock option in the requireHumanInput helper to capture that the tool call has been requested for the user.
const { issueCard }  = toolkit.requireHumanInput(
  { issueCard: issueCardTool },
  {
    // Keep track of the tool call state once it's been sent to Knock
    onAfterCallKnock: async (toolCall) =>
      agent.setToolCallStatus(toolCall.id, "requested"),
    // ... as before
  }
);
Finally, we then need to check the state when we’re processing the incoming webhook, and mark the tool call as approved (some code omitted for brevity).
export class AIAgent extends AIChatAgent {
  async handleIncomingWebhook(body: any) {
    const { toolkit } = await initializeToolkit(this);
    const deferredToolCall = toolkit.handleMessageInteraction(body);
    const toolCallId = result.toolCall.id;

    // Make sure this is a tool call that can be processed
    if (this.state.toolCalls[toolCallId] !== "requested") {
      return { error: "Tool call is not requested" };
    }

    if (result.interaction.status === "approved") {
      const toolCallResult = await toolkit.resumeToolExecution(result.toolCall);
      this.setToolCallStatus(toolCallId, "approved");
      // ... rest as before
    }
  }
}
Conclusion
Using the Agents SDK and Knock, it’s easy to build advanced human-in-the-loop experiences that defer tool calls.
Knock’s workflow builder and notification engine gives you building blocks to create sophisticated cross-channel messaging for your agents. You can easily create escalation flows that send messages through SMS, push, email, or Slack that respect the notification preferences of your users. Knock also gives you complete visibility into the messages your users are receiving.
The Durable Object abstraction underneath the Agents SDK means that we get a globally addressable agent process that’s easy to yield and resume back to. The persistent storage in the Durable Object means we can retain the complete chat history per-user, and any other state that’s required in the agent process to resume the agent with (like our tool calls). Finally, the serverless nature of the underlying Durable Object means we’re able to horizontally scale to support a large number of users with no effort.
If you’re looking to build your own AI Agent chat experience with a multiplayer human-in-the-loop experience, you’ll find the complete code from this guideavailable in GitHub.
Cloudflare Workers Builds is our CI/CD product that makes it easy to build and deploy Workers applications every time code is pushed to GitHub or GitLab. What makes Workers Builds special is that projects can be built and deployed with minimal configuration.Just hook up your project and let us take care of the rest!
But what happens when things go wrong, such as failing to install tools or dependencies? What usually happens is that we don’t fix the problem until a customer contacts us about it, at which point many other customers have likely faced the same issue. This can be a frustrating experience for both us and our customers because of the lag time between issues occurring and us fixing them.
We want Workers Builds to be reliable, fast, and easy to use so that developers can focus on building, not dealing with our bugs. That’s why we recently started building an error detection system that can detect, categorize, and surface all build issues occurring on Workers Builds, enabling us to proactively fix issues and add missing features.
In this post, we will dive into how we used the Cloudflare Developer Platform to check for issues across more than 1 million Durable Objects.
Background: Workers Builds architecture
Back in October 2024, we wrote abouthow we built Workers Builds entirely on the Workers platform. To recap, Builds is built using Workers, Durable Objects, Workers KV, R2, Queues, Hyperdrive, and a Postgres database. Some of these things were not present when launched back in October (for example, Queues and KV). But the core of the architecture is the same.
A client Worker receives GitHub/GitLab webhooks and stores build metadata in Postgres (via Hyperdrive). A build management Worker uses two Durable Object classes: a Scheduler class to find builds in Postgres that need scheduling, and a class called BuildBuddy to manage the lifecycle of a build. When a build needs to be started, Scheduler creates a new BuildBuddy instance which is responsible for creating a container for the build (usingCloudflare Containers), monitoring the container with health checks, and receiving build logs so that they can be viewed in the Cloudflare Dashboard.
In addition to this core scheduling logic, we have several Workers Queues for background work such as sending PR comments to GitHub/GitLab.
The problem: builds are failing
While this architecture has worked well for us so far, we found ourselves with a problem: compared toCloudflare Pages, a concerning percentage of builds were failing. We needed to dig deeper and figure out what was wrong, and understand how we could improve Workers Builds so that developers can focus more on shipping instead of build failures.
Types of build failures
Not all build failures are the same. We have several categories of failures that we monitor:
Initialization failures: when the container fails to start.
Clone failures: failing to clone the repository from GitHub/GitLab.
Build timeouts: builds that ran past the limit and were terminated by BuildBuddy.
Builds failing health checks: the container stopped responding to health checks, e.g. the container crashed for an unknown reason.
Failure to install tools or dependencies.
Failed user build/deploy commands.
The first few failure types were straightforward, and we’ve been able to track down and fix issues in our build system and control plane to improve what we call “build completion rate”. We define build completion as the following:
We successfully started the build.
We attempted to install tools/dependencies (considering failures as “user error”).
We attempted to run the user-defined build/deploy commands (again, considering failures as “user error”).
We successfully marked the build as stopped in our database.
For example, we had a bug where builds for a deleted Worker would attempt to run and continuously fail, which affected our build completion rate metric.
User error
We’ve made a lot of progress improving the reliability of build and container orchestration, but we had a significant percentage of build failures in the “user error” metric. We started asking ourselves “is this actually user error? Or is there a problem with the product itself?”
This presented a challenge because questions like “did the build command fail due to a bug in the build system, or user error?” are a lot harder to answer than pass/fail issues like failing to create a container for the build. To answer these questions, we had to build something new, something smarter.
Build logs
The most obvious way to determine why a build failed is to look at its logs. When spot-checking build failures, we can typically identify what went wrong. For example, some builds fail to install dependencies because of an out of date lockfile (e.g. package-lock.json out of date with package.json). But looking through build failures one by one doesn’t scale. We didn’t want engineers looking through customer build logs without at least suspecting that there was an issue with our build system that we could fix.
Automating error detection
At this point, next steps were clear: we needed an automated way to identify why a build failed based on build logs, and provide a way for engineers to see what the top issues were while ensuring privacy (e.g. removing account-specific identifiers and file paths from the aggregate data).
Detecting errors in build logs using Workers Queues
The first thing we needed was a way to categorize build errors after a build fails. To do this, we created a queue named BuildErrorsQueue to process builds and look for errors. After a build fails, BuildBuddy will send the build ID to BuildErrorsQueue which fetches the logs, checks for issues, and saves results to Postgres.
We started out with a few static patterns to match things like Wrangler errors in log lines:
It wouldn’t be useful if all Wrangler errors were grouped under a single generic “wrangler_error” code, so we further grouped them by normalizing the log lines into groups:
function getWranglerLogGroupFromLogLine(
  logLine: LogLine,
  regexMatchers: RegexMatcher[]
): string {
  const original = logLine[2].trim().replaceAll(/[\t\n\r]+/g, ' ')
  let message = original
  let group = original
  for (const { mustMatch, patterns, stopOnMatch, name, useNameAsGroup } of regexMatchers) {
    if (mustMatch !== undefined) {
      const matched = matchLineToRegexes(message, mustMatch)
      if (!matched) continue
    }
    if (patterns) {
      for (const [pattern, mask] of patterns) {
        message = message.replaceAll(pattern, mask)
      }
    }
    if (useNameAsGroup === true) {
      group = name
    } else {
      group = message
    }
    if (Boolean(stopOnMatch) && message !== original) break
  }
  return group
}

const wranglerRegexMatchers: RegexMatcher[] = [
  {
    name: 'could_not_resolve',
    // ✘ [ERROR] Could not resolve "./balance"
    // ✘ [ERROR] Could not resolve "node:string_decoder" (originally "string_decoder/")
    mustMatch: [/^✘ \[ERROR\] Could not resolve "[@\w :/\\.-]*"/i],
    stopOnMatch: true,
    patterns: [
      [/(?<=^✘ \[ERROR\] Could not resolve ")[@\w :/\\.-]*(?=")/gi, '<MODULE>'],
      [/(?<=\(originally ")[@\w :/\\.-]*(?=")/gi, '<MODULE>'],
    ],
  },
  {
    name: 'no_matching_export_for_import',
    // ✘ [ERROR] No matching export in "src/db/schemas/index.ts" for import "someCoolTable"
    mustMatch: [/^✘ \[ERROR\] No matching export in "/i],
    stopOnMatch: true,
    patterns: [
      [/(?<=^✘ \[ERROR\] No matching export in ")[@~\w:/\\.-]*(?=")/gi, '<MODULE>'],
      [/(?<=" for import ")[\w-]*(?=")/gi, '<IMPORT>'],
    ],
  },
  // ...many more added over time
]
Once we had our error detection matchers and normalizing logic in place, implementing the BuildErrorsQueue consumer was easy:
Here, we’re fetching logs from each build’s BuildBuddy Durable Object, detecting why it failed using the matchers we wrote, and saving errors to the Postgres DB. We also delete any existing errors for when we improve our error detection patterns to prevent subsequent runs from adding duplicate data to our database.
What about historical builds?
The BuildErrorsQueue was great for new builds, but this meant we still didn’t know why all the previous build failures happened other than “user error”. We considered only tracking errors in new builds, but this was unacceptable because it would significantly slow down our ability to improve our error detection system because each iteration would require us to wait days to identify issues we need to prioritize.
Problem: logs are stored across one million+ Durable Objects
Remember how every build has an associated BuildBuddy DO to store logs? This is a great design for ensuring our logging pipeline scales with our customers, but it presented a challenge when trying to aggregate issues based on logs because something would need to go through all historical builds (>1 million at the time) to fetch logs and detect why they failed.
If we were using Go and Kubernetes, we might solve this using a long-running container that goes through all builds and runs our error detection. But how do we solve this in Workers?
How do we backfill errors for historical builds?
At this point, we already had the Queue to process new builds. If we could somehow send all of the old build IDs to the queue, it could scan them all quickly usingQueues concurrent consumers to quickly work through all builds. We thought about hacking together a local script to fetch all of the log IDs and sending them to an API to put them on a queue. But we wanted something more secure and easier to use so that running a new backfill was as simple as an API call.
That’s when an idea hit us: what if we used a Durable Object with alarms to fetch a range of builds and send them to BuildErrorsQueue? At first, it seemed far-fetched, given that Durable Object alarms have a limited amount of work they can do per invocation. But wait, ifAI Agents built on Durable Objects can manage background tasks, why can’t we fetch millions of build IDs and forward them to queues?
Building a Build Errors Agent with Durable Objects
The idea was simple: create a Durable Object class named BuildErrorsAgent and run a single instance that loops through the specified range of builds in the database and sends them to BuildErrorsQueue.
The first thing we did was set up an RPC method to start a backfill and save the parameters inDurable Object KV storage so that it can be read each time the alarm executes:
async start({
  min_build_id,
  max_build_id,
}: {
  min_build_id: BuildRecord['build_id']
  max_build_id: BuildRecord['build_id']
}): Promise<void> {
  logger.setTags({ handler: 'start', environment: this.env.ENVIRONMENT })
  try {
    if (min_build_id < 0) throw new Error('min_build_id cannot be negative')
    if (max_build_id < min_build_id) {
      throw new Error('max_build_id cannot be less than min_build_id')
    }
    const [started_on, stopped_on] = await Promise.all([
      this.kv.get('started_on'),
      this.kv.get('stopped_on'),
    ])
    await match({ started_on, stopped_on })
      .with({ started_on: P.not(null), stopped_on: P.nullish }, () => {
        throw new Error('BuildErrorsAgent is already running')
      })
      .otherwise(async () => {
        // delete all existing data and start queueing failed builds
        await this.state.storage.deleteAlarm()
        await this.state.storage.deleteAll()
        this.kv.put('started_on', new Date())
        this.kv.put('config', { min_build_id, max_build_id })
        void this.state.storage.setAlarm(this.getNextAlarmDate())
      })
  } catch (e) {
    this.sentry.captureException(e)
    throw e
  }
}
The most important part of the implementation is the alarm that runs every second until the job is complete. Each alarm invocation has the following steps:
Set a new alarm (always first to ensure an error doesn’t cause it to stop).
Retrieve state from KV.
Validate that the agent is supposed to be running:
Ensure the agent is supposed to be running.
Ensure we haven’t reached the max build ID set in the config.
Finally, queue up another batch of builds by querying Postgres and sending to the BuildErrorsQueue.
async alarm(): Promise<void> {
  logger.setTags({ handler: 'alarm', environment: this.env.ENVIRONMENT })
  try {
    void this.state.storage.setAlarm(Date.now() + 1000)
    const kvState = await this.getKVState()
    this.sentry.setContext('BuildErrorsAgent', kvState)
    const ctxLogger = logger.withFields({ state: JSON.stringify(kvState) })

    await match(kvState)
      .with({ started_on: P.nullish }, async () => {
        ctxLogger.info('BuildErrorsAgent is not started, cancelling alarm')
        await this.state.storage.deleteAlarm()
      })
      .with({ stopped_on: P.not(null) }, async () => {
        ctxLogger.info('BuildErrorsAgent is stopped, cancelling alarm')
        await this.state.storage.deleteAlarm()
      })
      .with(
        // we should never have started_on set without config set, but just in case
        { started_on: P.not(null), config: P.nullish },
        async () => {
          const msg =
            'BuildErrorsAgent started but config is empty, stopping and cancelling alarm'
          ctxLogger.error(msg)
          this.sentry.captureException(new Error(msg))
          this.kv.put('stopped_on', new Date())
          await this.state.storage.deleteAlarm()
        }
      )
      .when(
        // make sure there are still builds to enqueue
        (s) =>
          s.latest_build_id !== null &&
          s.config !== null &&
          s.latest_build_id >= s.config.max_build_id,
        async () => {
          ctxLogger.info('BuildErrorsAgent job complete, cancelling alarm')
          this.kv.put('stopped_on', new Date())
          await this.state.storage.deleteAlarm()
        }
      )
      .with(
        {
          started_on: P.not(null),
          stopped_on: P.nullish,
          config: P.not(null),
          latest_build_id: P.any,
        },
        async ({ config, latest_build_id }) => {
          // 1. select batch of ~1000 builds
          // 2. send them to Queues 100 at a time, updating
          //    latest_build_id after each batch is sent
          const failedBuilds = await this.store.builds.selectFailedBuilds({
            min_build_id: latest_build_id !== null ? latest_build_id + 1 : config.min_build_id,
            max_build_id: config.max_build_id,
            limit: 1000,
          })
          if (failedBuilds.length === 0) {
            ctxLogger.info(`BuildErrorsAgent: ran out of builds, stopping and cancelling alarm`)
            this.kv.put('stopped_on', new Date())
            await this.state.storage.deleteAlarm()
          }

          for (
            let i = 0;
            i < BUILDS_PER_ALARM_RUN && i < failedBuilds.length;
            i += QUEUES_BATCH_SIZE
          ) {
            const batch = failedBuilds
              .slice(i, QUEUES_BATCH_SIZE)
              .map((build) => ({ body: build }))

            if (batch.length === 0) {
              ctxLogger.info(`BuildErrorsAgent: ran out of builds in current batch`)
              break
            }
            ctxLogger.info(
              `BuildErrorsAgent: sending ${batch.length} builds to build errors queue`
            )
            await this.env.BUILD_ERRORS_QUEUE.sendBatch(batch)
            this.kv.put(
              'latest_build_id',
              Math.max(...batch.map((m) => m.body.build_id).concat(latest_build_id ?? 0))
            )

            this.kv.put(
              'total_builds_processed',
              ((await this.kv.get('total_builds_processed')) ?? 0) + batch.length
            )
          }
        }
      )
      .otherwise(() => {
        const msg = 'BuildErrorsAgent has nothing to do - this should never happen'
        this.sentry.captureException(msg)
        ctxLogger.info(msg)
      })
  } catch (e) {
    this.sentry.captureException(e)
    throw e
  }
}
Using pattern matching with ts-pattern made it much easier to understand what states we were expecting and what will happen compared to procedural code. We considered using a more powerful library like XState, but decided on ts-pattern due to its simplicity.
Running the backfill
Once everything rolled out, we were able to trigger an errors backfill for over a million failed builds in a couple of hours with a single API call, categorizing 80% of failed builds on the first run. With a fast backfill process, we were able to iterate on our regex matchers to further refine our error detection and improve error grouping. Here’s what the error list looks like in our staging environment:
Fixes and improvements
Having a better understanding of what’s going wrong has already enabled us to make several improvements:
Fixed multiple edge-cases where the wrong package manager was used in TypeScript/JavaScript projects.
Added support for bun.lock (previously only checked for bun.lockb).
Fixed several edge cases where build caching did not work in monorepos.
Projects that use a runtime.txt file to specify a Python version no longer fail.
….and more!
We’re still working on fixing other bugs we’ve found, but we’re making steady progress. Reliability is a feature we’re striving for in Workers Builds, and this project has helped us make meaningful progress towards that goal. Instead of waiting for people to contact support for issues, we’re able to proactively identify and fix issues (and catch regressions more easily).
One of the great things about building on the Developer Platform is how easy it is to ship things. The core of this error detection pipeline (the Queue and Durable Object) only took two days to build, which meant we could spend more time working on improving Workers Builds instead of spending weeks on the error detection pipeline itself.
What’s next?
In addition to continuing to improve build reliability and speed, we’ve also started thinking about other ways to help developers build their applications on Workers. For example, we built aBuilds MCP server that allows users to debug builds directly in Cursor/Claude/etc. We’re also thinking about ways we can expose these detected issues in the Cloudflare Dashboard so that users can identify issues more easily without scrolling through hundreds of logs.
Ready to get started?
Building applications on Workers has never been easier! Try deploying a Durable Object-backed chat application with Workers Builds:
Streamable HTTP Transport: The Agents SDK now supports the new Streamable HTTP transport, allowing you to future-proof your MCP server. Our implementation allows your MCP server to simultaneously handle both the new Streamable HTTP transport and the existing SSE transport, maintaining backward compatibility with all remote MCP clients.
Deploy MCP servers written in Python: In 2024, we introduced first-class Python language support in Cloudflare Workers, and now you can build MCP servers on Cloudflare that are entirely written in Python.
Click “Deploy to Cloudflare” to get started with a remote MCP server that supports the new Streamable HTTP transport method, with backwards compatibility with the SSE transport.
Streamable HTTP: A simpler way for AI agents to communicate with services via MCP
The MCP spec was updated on March 26 to introduce a new transport mechanism for remote MCP, called Streamable HTTP. The new transport simplifies how AI agents can interact with services by using a single HTTP endpoint for sending and receiving responses between the client and the server, replacing the need to implement separate endpoints for initializing the connection and for sending messages.
Upgrading your MCP server to use the new transport method
If you’ve already built a remote MCP server on Cloudflare using the Cloudflare Agents SDK, then adding support for Streamable HTTP is straightforward. The SDK has been updated to support both the existing Server-Sent Events (SSE) transport and the new Streamable HTTP transport concurrently.
Here’s how you can configure your server to handle both transports:
Use MyMcpAgent.serveSSE('/sse') for the existing SSE transport. Previously, this would have been MyMcpAgent.mount('/sse'), which has been kept as an alias.
Add a new path with MyMcpAgent.serve('/mcp') to support the new Streamable HTTP transport
That’s it! With these few lines of code, your MCP server will support both transport methods, making it compatible with both existing and new clients.
Using Streamable HTTP from an MCP client
While most MCP clients haven’t yet adopted the new Streamable HTTP transport, you can start testing it today using mcp-remote, an adapter that lets MCP clients like Claude Desktop that otherwise only support local connections work with remote MCP servers. This tool allows any MCP client to connect to remote MCP servers via either SSE or Streamable HTTP, even if the client doesn’t natively support remote connections or the new transport method.
So, what’s new with Streamable HTTP?
Initially, remote MCP communication between AI agents and services used a single connection but required interactions with two different endpoints: one endpoint (/sse) to establish a persistent Server-Sent Events (SSE) connection that the client keeps open for receiving responses and updates from the server, and another endpoint (/sse/messages) where the client sends requests for tool calls.
While this works, it’s like having a conversation with two phones, one for listening and one for speaking. This adds complexity to the setup, makes it harder to scale, and requires connections to be kept open for long periods of time. This is because SSE operates as a persistent one-way channel where servers push updates to clients. If this connection closes prematurely, clients will miss responses or updates sent from the MCP server during long-running operations.
The new Streamable HTTP transport addresses these challenges by enabling:
Communication through a single endpoint: All MCP interactions now flow through one endpoint, eliminating the need to manage separate endpoints for requests and responses, reducing complexity.
Bi-directional communication: Servers can send notifications and requests back to clients on the same connection, enabling the server to prompt for additional information or provide real-time updates.
Automatic connection upgrades: Connections start as standard HTTP requests, but can dynamically upgrade to SSE (Server-Sent Events) to stream responses during long-running tasks.
Now, when an AI agent wants to call a tool on a remote MCP server, it can do so with a single POST request to one endpoint (/mcp). Depending on the tool call, the server will either respond immediately or decide to upgrade the connection to use SSE to stream responses or notifications as they become available — all over the same request.
Our current implementation of Streamable HTTP provides feature parity with the previous SSE transport. We’re actively working to implement the full capabilities defined in the specification, including resumability, cancellability, and session management to enable more complex, reliable, and scalable agent-to-agent interactions.
What’s coming next?
The MCP specification is rapidly evolving, and we’re committed to bringing these changes to the Agents SDK to keep your MCP server compatible with all clients. We’re actively tracking developments across both transport and authorization, adding support as they land, and maintaining backward compatibility to prevent breaking changes as adoption grows. Our goal is to handle the complexity behind the scenes, so you can stay focused on building great agent experiences.
On the transport side, here are some of the improvements coming soon to the Agents SDK:
Resumability: If a connection drops during a long-running operation, clients will be able to resume exactly where they left off without missing any responses. This eliminates the need to keep connections open continuously, making it ideal for AI agents that run for hours.
Cancellability: Clients will have explicit mechanisms to cancel operations, enabling cleaner termination of long-running processes.
Session management: We’re implementing secure session handling with unique session IDs that maintain state across multiple connections, helping build more sophisticated agent-to-agent communication patterns.
Deploying Python MCP Servers on Cloudflare
In 2024, we introduced Python Workers, which lets you write Cloudflare Workers entirely in Python. Now, you can use them to build and deploy remote MCP servers powered by the Python MCP SDK — a library for defining tools and resources using regular Python functions.
You can deploy a Python MCP server to your Cloudflare account with the button below, or read the code here.
Here’s how you can define tools and resources in the MCP server:
class FastMCPServer(DurableObject):
    def __init__(self, ctx, env):
        self.ctx = ctx
        self.env = env
        from mcp.server.fastmcp import FastMCP
        self.mcp = FastMCP("Demo")

        @mcp.tool()
        def calculate_bmi(weight_kg: float, height_m: float) -> float:
            """Calculate BMI given weight in kg and height in meters"""
            return weight_kg / (height_m**2)

        @mcp.resource("greeting://{name}")
        def get_greeting(name: str) -> str:
            """Get a personalized greeting"""
            return f"Hello, {name}!"

        self.app = mcp.sse_app()

    async def call(self, request):
        import asgi
        return await asgi.fetch(self.app, request, self.env, self.ctx)


async def on_fetch(request, env):
    id = env.ns.idFromName("example")
    obj = env.ns.get(id)
    return await obj.call(request)
If you’re already building APIs withFastAPI, a popular Python package for quickly building high performance API servers, you can use FastAPI-MCP to expose your existing endpoints as MCP tools. It handles the protocol boilerplate for you, making it easy to bring FastAPI-based services into the agent ecosystem.
On Cloudflare, you can start building today. We’re ready for you, and ready to help build with you. Email us at [email protected], and we’ll help get you going. There’s lots more to come with MCP, and we’re excited to see what you build.
Super Slurper is Cloudflare’s data migration tool that is designed to make large-scale data transfers between cloud object storage providers and Cloudflare R2 easy. Since its launch, thousands of developers have used Super Slurper to move petabytes of data from AWS S3, Google Cloud Storage, and other S3-compatible services to R2.
But we saw an opportunity to make it even faster. We rearchitected Super Slurper from the ground up using our Developer Platform — building on Cloudflare Workers, Durable Objects, and Queues — and improved transfer speeds by up to 5x. In this post, we’ll dive into the original architecture, the performance bottlenecks we identified, how we solved them, and the real-world impact of these improvements.
Initial architecture and performance bottlenecks
Super Slurper originally shared its architecture with SourcingKit, a tool built to bulk import images from AWS S3 into Cloudflare Images. SourcingKit was deployed on Kubernetes and ran alongside the Images service. When we started building Super Slurper, we split it into its own Kubernetes namespace and introduced a few new APIs to make it easier to use for the object storage use case. This setup worked well and helped thousands of developers move data to R2.
However, it wasn’t without its challenges. SourcingKit wasn’t designed to handle the scale required for large, petabytes-scale transfers. SourcingKit, and by extension Super Slurper, operated on Kubernetes clusters located in one of our core data centers, meaning it had to share compute resources and bandwidth with Cloudflare’s control plane, analytics, and other services. As the number of migrations grew, these resource constraints became a clear bottleneck.
For a service transferring data between object storage providers, the job is simple: list objects from the source, copy them to the destination, and repeat. This is exactly how the original Super Slurper worked. We listed objects from the source bucket, pushed that list to a Postgres-based queue (pg_queue), and then pulled from this queue at a steady pace to copy objects over. Given the scale of object storage migrations, bandwidth usage was inevitably going to be high. This made it challenging to scale.
To address the bandwidth constraints operating solely in our core data center, we introduced Cloudflare Workers into the mix. Instead of handling the copying of data in our core data center, we started calling out to a Worker to do the actual copying:
As Super Slurper’s usage grew, so did our Kubernetes resource consumption. A significant amount of time during data transfers was spent waiting on network I/O or storage, and not actually doing compute-intensive tasks. So we didn’t need more memory or more CPU, we needed more concurrency.
To keep up with demand, we kept increasing the replica count. But eventually, we hit a wall. We were dealing with scalability challenges when running on the order of tens of pods when we wanted multiple orders of magnitude more.
We decided to rethink the entire approach from first principles, instead of leaning on the architecture we had inherited. In about a week, we built a rough proof of concept using Cloudflare Workers, Durable Objects, and Queues. We listed objects from the source bucket, pushed them into a queue, and then consumed messages from the queue to initiate transfers. Although this sounds very similar to what we did in the original implementation, building on our Developer Platform allowed us to automatically scale an order of magnitude higher than before.
Cloudflare Queues: Enables asynchronous object transfers and auto-scales to meet the number of objects being migrated.
Cloudflare Workers: Runs lightweight compute tasks without the overhead of Kubernetes and optimizes where in the world each part of the process runsfor lower latency and better performance.
SQLite-backed Durable Objects (DOs): Acts as a fully distributed database, eliminating the limitations of a single PostgreSQL instance.
Hyperdrive: Provides fast access to historical job data from the original PostgreSQL database, keeping it as an archive store.
We ran a few tests and found that our proof of concept was slower than the original implementation for small transfers (a few hundred objects), but it matched and eventually exceeded the performance of the original as transfers scaled into the millions of objects. That was the signal we needed to invest the time to take our proof of concept to production.
We removed our proof of concept hacks, worked on stability, and found new ways to make transfers scale to even higher concurrency. After a few iterations, we landed on something we were happy with.
New architecture: Workers, Queues, and Durable Objects
Processing layer: managing the flow of migration
At the heart of our processing layer are queues, consumers, and workers. Here’s what the process looks like:
Kicking off a migration
When a client triggers a migration, it starts with a request sent to our API Worker. This worker takes the details of the migration, stores them in the database, and adds a message to the List Queue to start the process.
Listing source bucket objects
The List Queue Consumer is where things start to pick up. It pulls messages from the queue, retrieves object listings from the source bucket, applies any necessary filters, and stores important metadata in the database. Then, it creates new tasks by enqueuing object transfer messages into the Transfer Queue.
We immediately queue new batches of work, maximizing concurrency. A built-in throttling mechanism prevents us from adding more messages to our queues when unexpected failures occur, such as dependent systems going down. This helps maintain stability and prevents overload during disruptions.
Efficient object transfers
The Transfer Queue Consumer Workers pull object transfer messages from the queue, ensuring that each object is processed only once by locking the object key in the database. When the transfer finishes, the object is unlocked. For larger objects, we break them into manageable chunks and transfer them as multipart uploads.
Handling failures gracefully
Failures are inevitable in any distributed system, and we had to make sure we accounted for that. We implemented automatic retries for transient failures, so issues don’t interrupt the flow of the migration. But if something can’t be resolved with retries, the message goes into the Dead Letter Queue (DLQ), where it is logged for later review and resolution.
Job completion & lifecycle management
Once all the objects are listed and the transfers are in progress, the Lifecycle Queue Consumer keeps an eye on everything. It monitors the ongoing transfers, ensuring that no object is left behind. When all the transfers are complete, the job is marked as finished and the migration process wraps up.
Database layer: durable storage & legacy data retrieval
When building our new architecture, we knew we needed a robust solution to handle massive datasets while ensuring retrieval of historical job data. That’s where our combination of Durable Objects (DOs) and Hyperdrive came in.
Durable Objects
We gave each account a dedicated Durable Object to track migration jobs. Each job’s DO stores vital details, such as bucket names, user options, and job state. This ensured everything stayed organized and easy to manage. To support large migrations, we also added a Batch DO that manages all the objects queued for transfer, storing their transfer state, object keys, and any extra metadata.
As migrations scaled up to billions of objects, we had to get creative with storage. We implemented a sharding strategy to distribute request loads, preventing bottlenecks and working around SQLite DO’s 10 GB storage limit. As objects are transferred, we clean up their details, optimizing storage space along the way. It’s surprising how much storage a billion object keys can require!
Hyperdrive
Since we were rebuilding a system with years of migration history, we needed a way to preserve and access every past migration detail. Hyperdrive serves as a bridge to our legacy systems, enabling seamless retrieval of historical job data from our core PostgreSQL database. It’s not just a data retrieval mechanism, but an archive for complex migration scenarios.
Results: Super Slurper now transfers data to R2 up to 5x faster
So, after all of that, did we actually achieve our goal of making transfers faster?
We ran a test migration of 75,000 objects from AWS S3 to R2. With the original implementation, the transfer took 15 minutes and 30 seconds. After our performance improvements, the same migration completed in just 3 minutes and 25 seconds.
When production migrations started using the new service in February, we saw even greater improvements in some cases, especially depending on the distribution of object sizes. Super Slurper has been around for about two years. But the improved performance has led to it being able to move much more data — 35% of all objects copied by Super Slurper happened just in the last two months.
Challenges
One of the biggest challenges we faced with the new architecture was handling duplicate messages. There were a couple of ways duplicates could occur:
Queues provides at-least-once delivery, which means consumers may receive the same message more than once to guarantee delivery.
Failures and retries could also create apparent duplicates. For example, if a request to a Durable Object fails after the object has already been transferred, the retry could reprocess the same object.
If not handled correctly, this could result in the same object being transferred multiple times. To solve this, we implemented several strategies to ensure each object was accurately accounted for and only transferred once:
Since listing is sequential (e.g., to get object 2, you need the continuation token from listing object 1), we assign a sequence ID to each listing operation. This allows us to detect duplicate listings and prevent multiple processes from starting simultaneously. This is particularly useful because we don’t wait for database and queue operations to complete before listing the next batch. If listing 2 fails, we can retry it, and if listing 3 has already started, we can short-circuit unnecessary retries.
Each object is locked when its transfer begins, preventing parallel transfers of the same object. Once successfully transferred, the object is unlocked by deleting its key from the database. If a message for that object reappears later, we can safely assume it has already been transferred if the key no longer exists.
We rely on database transactions to keep our counts accurate. If an object fails to unlock, its count remains unchanged. Similarly, if an object key fails to be added to the database, the count isn’t updated, and the operation will be retried later.
As a last failsafe, we check whether the object already exists in the target bucket and was published after the start of our migration. If so, we assume it was transferred by our process (or another) and safely skip it.
What’s next for Super Slurper?
We’re always exploring ways to make Super Slurper faster, more scalable, and even easier to use — this is just the beginning.
Data migrations are still currently limited to 3 concurrent migrations per account, but we want to increase that limit. This will allow object prefixes to be split up into separate migrations and run in parallel, drastically increasing the speed at which a bucket can be migrated. For more information on Super Slurper and how to migrate data from existing object storage to R2, refer to our documentation.
P.S. As part of this update, we made the API much simpler to interact with, so migrations can now be managed programmatically!
I’m thrilled to share that Cloudflare has acquired Outerbase. This is such an amazing opportunity for us, and I want to explain how we got here, what we’ve built so far, and why we are so excited about becoming part of the Cloudflare team.
Databases are key to building almost any production application: you need to persist state for your users (or agents), be able to query it from a number of different clients, and you want it to be fast. But databases aren’t always easy to use: designing a good schema, writing performant queries, creating indexes, and optimizing your access patterns tends to require a lot of experience. Add that to exposing your data through easy-to-grok APIs that make the ‘right’ way to do things obvious, a great developer experience (from dashboard to CLI), and well… there’s a lot of work involved.
The Outerbase team is already getting to work on some big changes to how databases (and your data) are viewed, edited, and visualized from within Workers, and we’re excited to give you a few sneak peeks into what we’ll be landing as we get to work.
Database DX
When we first started Outerbase, we saw how complicated databases could be. Even experienced developers struggled with writing queries, indexing data, and locking down their data. Meanwhile, non-developers often felt locked out and that they couldn’t access the data they needed. We believed there had to be a better way. From day one, our goal was to make data accessible to everyone, no matter their skill level. While it started out by simply building a better database interface, it quickly evolved into something much more special.
Outerbase became a platform that helps you manage data in a way that feels natural. You can browse tables, edit rows, and run queries without having to deal with memorizing SQL structure. Even if you do know SQL, you can use Outerbase to dive in deeper and share your knowledge with your team. We also added visualization features so entire teams, both technical and not, could see what’s happening with their data at a glance. Then, with the growth of AI, we realized we could use it to handle many of the more complicated tasks.
One of our more exciting offerings is Starbase, a SQLite-compatible database built on top of Cloudflare’s Durable Objects. Our goal was never to simply wrap a legacy system in a shiny interface; we wanted to make it so easy to get started from day one with nothing, and Cloudflare’s Durable Objects gave us a way to easily manage and spin up databases for anyone who needed one. On top of them, we provided automatic REST APIs, row-level security, WebSocket support for streaming queries, and much more.
1 + 1 = 3
Our collaboration with Cloudflare first started last year, when we introduced a way for developers to import and manage their D1 databases inside Outerbase. We were impressed with how powerful Cloudflare’s tools are for deploying and scaling applications. As we worked together, we quickly saw how well our missions aligned. Cloudflare was building the infrastructure we wished we’d had when we first started, and we were building the data experience that many Cloudflare developers were asking for. This eventually led to the seemingly obvious decision of Outerbase joining Cloudflare — it just made so much sense.
Going forward, we’ll integrate Outerbase’s core features into Cloudflare’s platform. If you’re a developer using D1 or Durable Objects, you’ll start seeing features from Outerbase show up in the Cloudflare dashboard. Expect to see our data explorer for browsing and editing tables, new REST APIs, query editor with type-ahead functionality, real-time data capture, and more of the other tooling we’ve been refining over the last couple of years show up inside the Cloudflare dashboard.
As part of this transition, the hosted Outerbase cloud will shut down on October 15, 2025, which is about six months from now. We know some of you rely on Outerbase as it stands today, so we’re leaving the open-source repositories as they are.
You will still be able to self-host Outerbase if you prefer, and we’ll provide guidance on how to do that within your own Cloudflare account. Our main goal will be to ensure that the best parts of Outerbase become part of the Cloudflare developer experience, so you no longer have to make a choice (it’ll be obvious!).
Sneak peek
We’ve already done a lot of thinking about how we’re going to bring the best parts of Outerbase into D1, Durable Objects, Workflows, and Agents, and we’re going to a share a little about what will be landing over the course of Q2 2025 as the Outerbase team gets to work.
Specifically, we’ll be heads-down focusing on:
Adapting the powerful table viewer and query runner experiences to D1 and Durable Objects (amongst many other things!)
Making it easier to get started with Durable Objects: improving the experience in Wrangler (our CLI tooling), the Cloudflare dashboard, and how you plug into them from your client applications
Improvements to how you visualize the state of a Workflow and the (thousands to millions!) of Workflow instances you might have at any point in time
Pre- and post-query hooks for D1 that allow you to automatically register handlers that can act on your data
Bringing the Starbase API to D1, expanding D1’s existing REST API, and adding WebSockets support — making it easier to use D1, even for applications hosted outside of Workers.
We have already started laying the groundwork for these changes. In the coming weeks, we’ll release a unified data explorer for D1 and Durable Objects that borrows heavily from the Outerbase interface you know.
Bringing Outerbase’s Data Explorer into the Cloudflare Dashboard
We’ll also tie some of Starbase’s features directly into Cloudflare’s platform, so you can tap into its unique offerings like pre- and post-query hooks or row-level security right from your existing D1 databases and Durable Objects:
const beforeQuery = ({ sql, params }) => {
    // Prevent unauthorized queries
    if (!isAllowedQuery(sql)) throw new Error('Query not allowed');
};

const afterQuery = ({ sql, result }) => {
    // Basic PII masking example
    for (const row of result) {
        if ('email' in row) row.email = '[redacted]';
    }
};

// Execute the query with pre- and post- query hooks
const { results } = await env.DB.prepare("SELECT * FROM users;", beforeQuery, afterQuery);
Define hooks on your D1 queries that can be re-used, shared and automatically executed before or after your queries run.
This should give you more clarity and control over your data, as well as new ways to secure and optimize it.
Rethinking the Durable Objects getting started experience
We have even begun optimizing the Cloudflare dashboard experience around Durable Objects and D1 to improve the empty state, provide more Getting Started resources, and overall, make managing and tracking your database resources even easier.
For those of you who’ve supported us, given us feedback, and stuck with us as we grew: thank you. You have helped shape Outerbase into what it is today. This acquisition means we can pour even more resources and attention into building the data experience we’ve always wanted to deliver. Our hope is that, by working as part of Cloudflare, we can help reach even more developers by building intuitive experiences, accelerating the speed of innovation, and creating tools that naturally fit into your workflows.
This is a big step for Outerbase, and we couldn’t be more excited. Thank you for being part of our journey so far. We can’t wait to show you what we’ve got in store as we continue to make data more accessible, intuitive, and powerful — together with Cloudflare.
What’s next?
We’re planning to get to work on some of the big changes to how you interact with your data on Cloudflare, starting with D1 and Durable Objects.
We’ll also be ensuring we bring a great developer experience to the broader database & storage platform on Cloudflare, including how you access data in Workers KV, R2, Workflows and even your AI Agents (just to name a few).
As engineers, we’re obsessed with efficiency and automating anything we find ourselves doing more than twice. If you’ve ever done this, you know that the happy path is always easy, but the second the inputs get complex, automation becomes really hard. This is because computers have traditionally required extremely specific instructions in order to execute.
The state of AI models available to us today has changed that. We now have access to computers that can reason, and make judgement calls in lieu of specifying every edge case under the sun.
That’s what AI agents are all about.
Today we’re excited to share a few announcements on how we’re making it eveneasier to build AI agents on Cloudflare, including:
agents-sdk — a new JavaScript framework for building AI agents
Updates to Workers AI: structured outputs, tool calling, and longer context windows for Workers AI, Cloudflare’s serverless inference engine
We truly believe that Cloudflare is the ideal platform for building Agents and AI applications (more on why below), and we’re constantly working to make it better — you can expect to see more announcements from us in this space in the future.
Before we dive deep into the announcements, we wanted to give you a quick primer on agents. If you are familiar with agents, feel free to skip ahead.
What are agents?
Agents are AI systems that can autonomously execute tasks by making decisions about tool usage and process flow. Unlike traditional automation that follows predefined paths, agents can dynamically adapt their approach based on context and intermediate results. Agents are also distinct from co-pilots (e.g. traditional chat applications) in that they can fully automate a task, as opposed to simply augmenting and extending human input.
Agents → non-linear, non-deterministic (can change from run to run)
Workflows → linear, deterministic execution paths
Co-pilots → augmentative AI assistance requiring human intervention
Example: booking vacations
If this is your first time working with, or interacting with agents, this example will illustrate how an agent works within a context like booking a vacation.
Imagine you’re trying to book a vacation. You need to research flights, find hotels, check restaurant reviews, and keep track of your budget.
Traditional workflow automation
A traditional automation system follows a predetermined sequence: it can take inputs such as dates, location, and budget, and make calls to predefined APIs in a fixed order. However, if any unexpected situations arise, such as flights being sold out, or the specified hotels being unavailable, it cannot adapt.
AI co-pilot
A co-pilot acts as an intelligent assistant that can provide hotel and itinerary recommendations based on your preferences. If you have questions, it can understand and respond to natural language queries and offer guidance and suggestions. However, it is unable to take the next steps to execute the end-to-end action on its own.
Agent
An agent combines AI’s ability to make judgements and call the relevant tools to execute the task. An agent’s output will be nondeterministic given: real-time availability and pricing changes, dynamic prioritization of constraints, ability to recover from failures, and adaptive decision-making based on intermediate results. In other words, if flights or hotels are unavailable, an agent can reassess and suggest a new itinerary with altered dates or locations, and continue executing your travel booking.
agents-sdk — the framework for building agents
You can now add agent powers to any existing Workers project with just one command:
$ npm i agents-sdk
… or if you want to build something from scratch, you can bootstrap your project with the agents-starter template:
$ npm create cloudflare@latest agents-starter --template=cloudflare/agents-starter
// ... and then deploy it
$ npm run deploy
agents-sdk is a framework that allows you to build agents — software that can autonomously execute tasks — and deploy them directly into production on Cloudflare Workers.
Your agent can start with the basics and act on HTTP requests…
import { Agent } from "agents-sdk";

export class IntelligentAgent extends Agent {
  async onRequest(request) {
    // Transform intention into response
    return new Response("Ready to assist.");
  }
}
Although this is just the initial release of agents-sdk, we wanted to ship more than just a thin wrapper over an existing library. Agents can communicate with clients in real time, persist state, execute long-running tasks on a schedule, send emails, run asynchronous workflows, browse the web, query data from your Postgres database, call AI models, and support human-in-the-loop use-cases. All of this works today, out of the box.
For example, you can build a powerful chat agent with the AIChatAgent class:
// src/index.ts
export class Chat extends AIChatAgent<Env> {
  /**
   * Handles incoming chat messages and manages the response stream
   * @param onFinish - Callback function executed when streaming completes
   */
  async onChatMessage(onFinish: StreamTextOnFinishCallback<any>) {
    // Create a streaming response that handles both text and tool outputs
    return agentContext.run(this, async () => {
      const dataStreamResponse = createDataStreamResponse({
        execute: async (dataStream) => {
          // Process any pending tool calls from previous messages
          // This handles human-in-the-loop confirmations for tools
          const processedMessages = await processToolCalls({
            messages: this.messages,
            dataStream,
            tools,
            executions,
          });

          // Initialize OpenAI client with API key from environment
          const openai = createOpenAI({
            apiKey: this.env.OPENAI_API_KEY,
          });

          // Cloudflare AI Gateway
          // const openai = createOpenAI({
          //   apiKey: this.env.OPENAI_API_KEY,
          //   baseURL: this.env.GATEWAY_BASE_URL,
          // });

          // Stream the AI response using GPT-4
          const result = streamText({
            model: openai("gpt-4o-2024-11-20"),
            system: `
              You are a helpful assistant that can do various tasks. If the user asks, then you can also schedule tasks to be executed later. The input may have a date/time/cron pattern to be input as an object into a scheduler The time is now: ${new Date().toISOString()}.
              `,
            messages: processedMessages,
            tools,
            onFinish,
            maxSteps: 10,
          });

          // Merge the AI response stream with tool execution outputs
          result.mergeIntoDataStream(dataStream);
        },
      });

      return dataStreamResponse;
    });
  }
  async executeTask(description: string, task: Schedule<string>) {
    await this.saveMessages([
      ...this.messages,
      {
        id: generateId(),
        role: "user",
        content: `scheduled message: ${description}`,
      },
    ]);
  }
}

export default {
  async fetch(request: Request, env: Env, ctx: ExecutionContext) {
    if (!env.OPENAI_API_KEY) {
      console.error(
        "OPENAI_API_KEY is not set, don't forget to set it locally in .dev.vars, and use `wrangler secret bulk .dev.vars` to upload it to production"
      );
      return new Response("OPENAI_API_KEY is not set", { status: 500 });
    }
    return (
      // Route the request to our agent or return 404 if not found
      (await routeAgentRequest(request, env)) ||
      new Response("Not found", { status: 404 })
    );
  },
} satisfies ExportedHandler<Env>;
… and connect to your Agent with any React-based front-end with the useAgent hook that can automatically establish a bidirectional WebSocket, sync client state, and allow you to build Agent-based applications without a mountain of bespoke code:
We spent some time thinking about the production story here too: an agent framework that absolves itself of the hard parts — durably persisting state, handling long-running tasks & loops, and horizontal scale — is only going to get you so far. Agents built with agents-sdk can be deployed directly to Cloudflare and run on top of Durable Objects — which you can think of as stateful micro-servers that can scale to tens of millions — and are able to run wherever they need to. Close to a user for low-latency, close to your data, and/or anywhere in between.
agents-sdk also exposes:
Integration with React applications via a useAgent hook that can automatically set up a WebSocket connection between your app and an agent
An AIChatAgent extension that makes it easier to build intelligent chat agents
State management APIs via this.setState as well as a native sql API for writing and querying data within each Agent
State synchronization between frontend applications and the agent state
Agent routing, enabling agent-per-user or agent-per-workflow use-cases. Spawn millions (or tens of millions) of agents without having to think about how to make the infrastructure work, provision CPU, or scale out storage.
Over the coming weeks, expect to see even more here: tighter integration with email APIs to enable more human-in-the-loop use-cases, hooks into WebRTC for voice & video interactivity, a built-in evaluation (evals) framework, and the ability to self-host agents on your own infrastructure.
We’re aiming high here: we think this is just the beginning of what agents are capable of, and we think we can make Workers the best place (but not the only place) to build & run them.
JSON mode, longer context windows, and improved tool calling in Workers AI
When users express needs conversationally, tool calling converts these requests into structured formats like JSON that APIs can understand and process, allowing the AI to interact with databases, services, and external systems. This is essential for building agents, as it allows users to express complex intentions in natural language, and AI to decompose these requests, call appropriate tools, evaluate responses and deliver meaningful outcomes.
When using tool calling or building AI agents, the text generation model must respond with valid JSON objects rather than natural language. Today, we’re adding JSON mode support to Workers AI, enabling applications to request a structured output response when interacting with AI models. Here’s a request to @cf/meta/llama-3.1-8b-instruct-fp8-fast using JSON mode:
As you can see, the model is complying with the JSON schema definition in the request and responding with a validated JSON object. JSON mode is compatible with OpenAI’s response_format implementation:
We will continue extending this list to keep up with new, and requested models.
Lastly, we are changing how we restrict the size of AI requests to text generation models, moving from byte-counts to token-counts, introducing the concept of context window and raising the limits of the models in our catalog.
In generative AI, the context window is the sum of the number of input, reasoning, and completion or response tokens a model supports. You can now find the context window limit on each model page in our developer documentation and decide which suits your requirements and use case.
JSON mode is also the perfect companion when using function calling. You can use structured JSON outputs with traditional function calling or the Vercel AI SDK via the workers-ai-provider.
workers-ai-provider 0.1.1
One of the most common ways to build with AI tooling today is by using the popular AI SDK. Cloudflare’s provider for the AI SDK makes it easy to use Workers AI the same way you would call any other LLM, directly from your code.
A key part of building agents is using LLMs for routing, and making decisions on which tools to call next, and summarizing structured and unstructured data. All of these things need to happen quickly, as they are on the critical path of the user-facing experience.
Workers AI, with its globally distributed fleet of GPUs, is a perfect fit for smaller, low-latency LLMs, so we’re excited to make it easy to use with tools developers are already familiar with.
Why build agents on Cloudflare?
Since launching Workers in 2017, we’ve been building a platform to allow developers to build applications that are fast, scalable, and cost-efficient from day one. We took a fundamentally different approach from the way code was previously run on servers, making a bet about what the future of applications was going to look like — isolates running on a global network, in a way that was truly serverless. No regions, no concurrency management, no managing or scaling infrastructure.
The release of Workers was just the beginning, and we continued shipping primitives to extend what developers could build. Some more familiar, like a key-value store (Workers KV), and some that we thought would play a role in enabling net new use cases like Durable Objects. While we didn’t quite predict AI agents (though “Agents” was one of the proposed names for Durable Objects), we inadvertently created the perfect platform for building them.
What do we mean by that?
A platform that only charges you for what you use (regardless of how long it takes)
To be able to run agents efficiently, you need a system that can seamlessly scale up and down to support the constant stop, go, wait patterns. Agents are basically long-running tasks, sometimes waiting on slow reasoning LLMs and external tools to execute. With Cloudflare, you don’t have to pay for long-running processes when your code is not executing. Cloudflare Workers is designed to scale down and only charge you for CPU time, as opposed to wall-clock time.
In many cases, especially when calling LLMs, the difference can be in orders of magnitude — e.g. 2–3 milliseconds of CPU vs. 10 seconds of wall-clock time. When building on Workers, we pass that difference on to you as cost savings.
Serverless AI Inference
We took a similar serverless approach when it comes to inference itself. When you need to call an AI model, you need it to be instantaneously available. While the foundation model providers offer APIs that make it possible to just call the LLM, if you’re running open-source models, LoRAs, or self-trained models, most cloud providers today require you to pre-provision resources for what your peak traffic will look like. This means that the rest of the time, you’re still paying for GPUs to sit there idle. With Workers AI, you can pay only when you’re calling our inference APIs, as opposed to unused infrastructure. In fact, you don’t have to think about infrastructure at all, which is the principle at the core of everything we do.
A platform designed for durable execution
Durable Objects and Workflows provide a robust programming model that ensures guaranteed execution for asynchronous tasks that require persistence and reliability. This makes them ideal for handling complex operations like long-running deep thinking LLM calls, human-in-the-loop approval processes, or interactions with unreliable third-party APIs. By maintaining state across requests and automatically handling retries, these tools create a resilient foundation for building sophisticated AI agents that can perform complex, multistep tasks without losing context or progress, even when operations take significant time to complete.
Lastly, new and updated agents documentation
Did you catch all of that?
No worries if not: we’ve updated our agents documentation to include everything we talked about above, from breaking down the basics of agents, to showing you how to tackle foundational examples of building with agents.
We’ve also updated our Workers prompt with knowledge of the agents-sdk library, so you can use Cursor, Windsurf, Zed, ChatGPT or Claude to help you build AI Agents and deploy them to Cloudflare.
Can’t wait to see what you build!
We’re just getting started, and we love to see all that you build. Please join our Discord, ask questions, and tell us what you’re building.
With the rapid advancements occurring in the AI space, developers face significant challenges in keeping up with the ever-changing landscape. New models and providers are continuously emerging, and understandably, developers want to experiment and test these options to find the best fit for their use cases. This creates the need for a streamlined approach to managing multiple models and providers, as well as a centralized platform to efficiently monitor usage, implement controls, and gather data for optimization.
AI Gateway is specifically designed to address these pain points. Since its launch in September 2023, AI Gateway has empowered developers and organizations by successfully proxying over 2 billion requests in just one year, as we highlighted during September’s Birthday Week. With AI Gateway, developers can easily store, analyze, and optimize their AI inference requests and responses in real time.
With our initial architecture, AI Gateway faced a significant challenge: the logs, those critical trails of data interactions between applications and AI models, could only be retained for 30 minutes. This limitation was not just a minor inconvenience; it posed a substantial barrier for developers and businesses needing to analyze long-term patterns, ensure compliance, or simply debug over more extended periods.
In this post, we’ll explore the technical challenges and strategic decisions behind extending our log storage capabilities from 30 minutes to being able to store billions of logs indefinitely. We’ll discuss the challenges of scale, the intricacies of data management, and how we’ve engineered a system that not only meets the demands of today, but is also scalable for the future of AI development.
Background
AI Gateway is built on Cloudflare Workers, a serverless platform that runs on the Cloudflare network, allowing developers to write small JavaScript functions that can execute at the point of need, near the user, on Cloudflare’s vast network of data centers, without worrying about platform scalability.
Our customers use multiple providers and models and are always looking to optimize the way they do inference. And, of course, in order to evaluate their prompts, performance, cost, and to troubleshoot what’s going on, AI Gateway’s customers need to store requests and responses. New requests show up within 15 seconds and customers can check a request’s cost, duration, number of tokens, and provide their feedback (thumbs up or down).
This scales in a way where an account can have multiple gateways and each gateway has its own settings. In our first implementation, a backend worker was responsible for storing Real Time Logs and other background tasks. However, in the rapidly evolving domain of artificial intelligence, where real-time data is as precious as the insights it provides, managing log data efficiently becomes paramount. We recognized that to truly empower our users, we needed to offer a solution where logs weren’t just transient records but could be stored permanently. Permanent log storage means developers can now track the performance, security, and operational insights of their AI applications over time, enabling not only immediate troubleshooting but also longitudinal studies of AI behavior, usage trends, and system health.
The diagram above describes our old architecture, which could only store 30 minutes of data.
Tracing the path of a request through the AI Gateway, as depicted in the sequence above:
A developer sends a new inference request, which is first received by our Gateway Worker.
The Gateway Worker then performs several checks: it looks for cached results, enforces rate limits, and verifies any other configurations set by the user for their gateway. Provided all conditions are met, it forwards the request to the selected inference provider (in this diagram, OpenAI).
The inference provider processes the request and sends back the response.
Simultaneously, as the response is relayed back to the developer, the request and response details are also dispatched to our Backend Worker. This worker’s role is to manage and store the log of this transaction.
The challenge: Store two billion logs
First step: real-time logs
Initially, the AI Gateway project stored both request metadata and the actual request bodies in a D1 database. This approach facilitated rapid development in the project’s infancy. However, as customer engagement grew, the D1 database began to fill at an accelerating rate, eventually retaining logs for only 30 minutes at a time.
To mitigate this, we first optimized the database schema, which extended the log retention to one hour. However, we soon encountered diminishing returns due to the sheer volume of byte data from the request bodies. Post-launch, it became clear that a more scalable solution was necessary. We decided to migrate the request bodies to R2 storage, significantly alleviating the data load on D1. This adjustment allowed us to incrementally extend log retention to 24 hours.
Consequently, D1 functioned primarily as a log index, enabling users to search and filter logs efficiently. When users needed to view details or download a log, these actions were seamlessly proxied through to R2.
This dual-system approach provided us with the breathing room to contemplate and develop more sophisticated storage solutions for the future.
Second step: persistent logs and Durable Object transactional storage
As our traffic surged, we encountered a growing number of requests from customers wanting to access and compare older logs.
Upon learning that the Durable Objects team was seeking beta testers for their new Durable Objects with SQLite, we eagerly signed up.
Originally, we considered Durable Objects as the ideal solution for expanding our log storage capacity, which required us to shard the logs by a unique string. Initially, this string was the account ID, but during a mid-development load test, we hit a cap at 10 million logs per Durable Object. This limitation meant that each account could only support up to this number of logs.
Given our commitment to the DO migration, we saw an opportunity rather than a constraint. To overcome the 10 million log limit per account, we refined our approach to shard by both account ID and gateway name. This adjustment effectively raised the storage ceiling from 10 million logs per account to 10 million per gateway. With the default setting allowing each account up to 10 gateways, the potential storage for each account skyrocketed to 100 million logs.
This strategic pivot not only enabled us to store a significantly larger number of logs. But also enhanced our flexibility in gateway management. Now, when a gateway is deleted, we can simply remove the corresponding Durable Object.
Additionally, this sharding method isolates high-volume request scenarios. If one customer’s heavy usage slows down log insertion, it only impacts their specific Durable Object, thereby preserving performance for other customers.
Taking a glance at the revised architecture diagram, we replaced the Backend Worker with our newly integrated Durable Object. The rest of the request flow remains unchanged, including the concurrent response to the user and the interaction with the Durable Object, which occurs in the fourth step.
Leveraging Cloudflare’s network, our Gateway Worker operates near the user’s location, which in turn positions the user’s Durable Object close by. This proximity significantly enhances the speed of log insertion and query operations.
Third step: managing thousands of Durable Objects
As the number of users and requests on AI Gateway grows, managing each unique Durable Object (DO) becomes increasingly complex. New customers join continuously, and we needed an efficient method to track each DO, ensure users stay within their 10 gateway limit, and manage the storage capacity for free users.
To address these challenges, we introduced another layer of control with a new Durable Object we’ve named the Account Manager. The primary function of the Account Manager is straightforward yet crucial: it keeps user activities in check.
Here’s how it works: before any Gateway commits a new log to permanent storage, it consults the Account Manager. This check determines whether the gateway is allowed to insert the log based on the user’s current usage and entitlements. The Account Manager uses its own SQLite database to verify the total number of rows a user has and their service level. If all checks pass, it signals the Gateway that the log can be inserted. It was paramount to guarantee that this entire validation process occurred in the background, ensuring that the user experience remains seamless and uninterrupted.
The Account Manager stays updated by periodically receiving data from each Gateway’s Durable Object. Specifically, after every 1000 inference requests, the Gateway sends an update on its total rows to the Account Manager, which then updates its local records. This system ensures that the Account Manager has the most current data when making its decisions.
Additionally, the Account Manager is responsible for monitoring customer entitlements. It tracks whether an account is on a free or paid plan, how many gateways a user is permitted to create, and the log storage capacity allocated to each gateway.
Through these mechanisms, the Account Manager not only helps in maintaining system integrity but also ensures fair usage across all users of AI Gateway.
AI evaluations and Durable Objects sharding
As we continue to develop evaluations to fully automatic and, in the future, use Large Language Models (LLMs), we are now taking the first step towards this goal and launching the open beta phase of comprehensive AI evaluations, centered on Human-in-the-Loop feedback.
This feature empowers users to create bespoke datasets from their application logs, thereby enabling them to score and evaluate the performance, speed, and cost-effectiveness of their models, with a primary focus on LLMs and automated scoring, analyzing the performance of LLMs, providing developers with objective, data-driven insights to refine their models.
To do this, developers require a reliable logging mechanism that persists logs from multiple gateways, storing up to 100 million logs in total (10 million logs per gateway, across 10 gateways). This represents a significant volume of data, as each request made through the AI Gateway generates a log entry, with some log entries potentially exceeding 50 MB in size.
This necessity leads us to work on the expansion of log storage capabilities. Since log storage is limited to 10 million logs per gateway, in future iterations, we aim to scale this capacity by implementing sharded Durable Objects (DO), allowing multiple Durable Objects per gateway to handle and store logs. This scaling strategy will enable us to store significantly larger volumes of logs, providing richer data for evaluations (using LLMs as a judge or from user input), all through AI Gateway.
Coming Soon
We are working on improving our existing Universal Endpoint, the next step on an enhanced solution that builds on existing fallback mechanisms to offer greater resilience, flexibility, and intelligence in request management.
Currently, when a provider encounters an error or is unavailable, our system falls back to an alternative provider to ensure continuity. The improved Universal Endpoint takes this a step further by introducing automatic retry capabilities, allowing failed requests to be reattempted before fallback is triggered. This significantly improves reliability by handling transient errors and increasing the likelihood of successful request fulfillment. It will look something like this:
The request to the improved Universal Endpoint system demonstrates how it handles multiple providers with integrated retry mechanisms and fallback logic. In this example, the first request is sent to a provider like OpenAI, asking it to generate a text-to-image prompt. The “retry” option ensures that transient issues don’t result in immediate failure.
The system’s ability to seamlessly switch between providers while applying retry strategies ensures higher reliability and robustness in managing requests. By leveraging fallback logic, the Improved Universal Endpoint can dynamically adapt to provider failures, ensuring that tasks are completed successfully even in complex, multi-step workflows.
In addition to retry logic, we will have the ability to inspect requests and responses and make dynamic decisions based on the content of the result. This enables developers to create conditional workflows where the system can adapt its behavior depending on the nature of the response, creating a highly flexible and intelligent decision-making process.
If you haven’t yet used AI Gateway, check out our developer documentation on how to get started. If you have any questions, reach out on our Discord channel.
Workflows, Cloudflare’s durable execution engine that allows you to build reliable, repeatable multi-step applications that scale for you, is now in open beta. Any developer with a free or paid Workers plan can build and deploy a Workflow right now: no waitlist, no sign-up form, no fake line around-the-block.
Open the src/index.ts file, poke around, start extending it, and deploy it with a quick wrangler deploy.
If you want to learn more about how Workflows works, how you can use it to build applications, and how we built it, read on.
Workflows? Durable Execution?
Workflows—which we announced back during Developer Week earlier this year—is our take on the concept of “Durable Execution”: the ability to build and execute applications that are durable in the face of errors, network issues, upstream API outages, rate limits, and (most importantly) infrastructure failure.
As over 2.4 million developers continue to build applications on top of Cloudflare Workers, R2, and Workers AI, we’ve noticed more developers building multi-step applications and workflows that process user data, transform unstructured data into structured, export metrics, persist state as they progress, and automatically retry & restart. But writing any non-trivial application and making it durable in the face of failure is hard: this is where Workflows comes in. Workflows manages the retries, emitting the metrics, and durably storing the state (without you having to stand up your own database) as the Workflow progresses.
What makes Workflows different from other takes on “Durable Execution” is that we manage the underlying compute and storage infrastructure for you. You’re not left managing a compute cluster and hoping it scales both up (on a Monday morning) and down (during quieter periods) to manage costs, or ensuring that you have compute running in the right locations. Workflows is built on Cloudflare Workers — our job is to run your code and operate the infrastructure for you.
As an example of how Workflows can help you build durable applications, assume you want to post-process file uploads from your users that were uploaded to an R2 bucket directly via a pre-signed URL. That post-processing could involve multiple actions: text extraction via a Workers AI model, calls to a third-party API to validate data, updating or querying rows in a database once the file has been processed… the list goes on.
But what each of these actions has in common is that it could fail. Maybe that upstream API is unavailable, maybe you get rate-limited, maybe your database is down. Having to write extensive retry logic around each action, manage backoffs, and (importantly) ensure your application doesn’t have to start from scratch when a later step fails is more boilerplate to write and more code to test and debug.
What’s a step, you ask? The core building block of every Workflow is the step: an individually retriable component of your application that can optionally emit state. That state is then persisted, even if subsequent steps were to fail. This means that your application doesn’t have to restart, allowing it to not only recover more quickly from failure scenarios, but it can also avoid doing redundant work. You don’t want your application hammering an expensive third-party API (or getting you rate limited) because it’s naively retrying an API call that you don’t have to.
Notably, a Workflow can have hundreds of steps: one of the Rules of Workflows is to encapsulate every API call or stateful action within your application into its own step. Each step can also define its own retry strategy, automatically backing off, adding a delay and/or (eventually) giving up after a set number of attempts.
await step.do(
	'make a call to write that could maybe, just might, fail',
	// Define a retry strategy
	{
		retries: {
			limit: 5,
			delay: '5 seconds',
			backoff: 'exponential',
		},
		timeout: '15 minutes',
	},
	async () => {
		// Do stuff here, with access to the state from our previous steps
		if (Math.random() > 0.5) {
			throw new Error('API call to $STORAGE_SYSTEM failed');
		}
	},
);
To illustrate this further, imagine you have an application that reads text files from an R2 storage bucket, pre-processes the text into chunks, generates text embeddings using Workers AI, and then inserts those into a vector database (like Vectorize) for semantic search.
In the Workflows programming model, each of those is a discrete step, and each can emit state. For example, each of the four actions below can be a discrete step.do call in a Workflow:
Reading the files from storage and emitting the list of filenames
Chunking the text and emitting the results
Generating text embeddings
Upserting them into Vectorize and capturing the result of a test query
You can also start to imagine that some steps, such as chunking text or generating text embeddings, can be broken down into even more steps — a step per file that we chunk, or a step per API call to our text embedding model, so that our application is even more resilient to failure.
Steps can be created programmatically or conditionally based on input, allowing you to dynamically create steps based on the number of inputs your application needs to process. You do not need to define all steps ahead of time, and each instance of a Workflow may choose to conditionally create steps on the fly.
Building Cloudflare on Cloudflare
As the Cloudflare Developer platform continues to grow, almost all of our own products are built on top of it. Workflows is yet another example of how we built a new product from scratch using nothing but Workers and its vast catalog of features and APIs. This section of the blog has two goals: to explain how we built it, and to demonstrate that anyone can create a complex application or platform with demanding requirements and multiple architectural layers on our stack, too.
To understand how Workflows uses Workers & Durable Objects, here’s the high-level overview of our architecture:
There are three main blocks in this diagram:
The user-facing APIs are where the user interacts with the platform, creating and deploying new workflows or instances, controlling them, and accessing their state and activity logs. These operations can be executed through our public API gateway using REST calls, a Worker script using bindings, Wrangler (Cloudflare’s developer platform command line tool), or via the Dashboard user interface.
The managed platform holds the internal configuration APIs running on a Worker implementing a catalog of REST endpoints, the binding shim, which is supported by another dedicated Worker, every account controller, and their correspondent workflow engines, all powered by SQLite-backed Durable Objects. This is where all the magic happens and what we are sharing more details about in this technical blog.
Finally, there are the workflow instances, essentially independent clones of the workflow application. Instances are user account-owned and have a one-to-one relationship with a managed engine that powers them. You can run as many instances and engines as you want concurrently.
Let’s get into more detail…
Configuration API and Binding Shim
The Configuration API and the Binding Shim are two stateless Workers; one receives REST API calls from clients calling our API Gateway directly, using Wrangler, or navigating the Dashboard UI, and the other is the endpoint for the Workflows binding, an efficient and authenticated interface to interact with the Cloudflare Developer Platform resources from a Workers script.
The configuration API worker uses HonoJS and Zod to implement the REST endpoints, which are declared in an OpenAPI schema and exported to our API Gateway, thus adding our methods to the Cloudflare API catalog.
import { swaggerUI } from '@hono/swagger-ui';
import { createRoute, OpenAPIHono, z } from '@hono/zod-openapi';
import { Hono } from 'hono';
...
api.openapi(
createRoute({
method: 'get',
path: '/',
request: {
query: PaginationParams,
},
responses: {
200: {
content: {
'application/json': {
schema: APISchemaSuccess(z.array(WorkflowWithInstancesCountSchema)),
},
},
description: 'List of all Workflows belonging to a account.',
},
},
}),
async (ctx) => {
...
},
);
...
api.route('/:workflow_name', routes.workflows);
api.route('/:workflow_name/instances', routes.instances);
api.route('/:workflow_name/versions', routes.versions);
These Workers perform two different functions, but they share a large portion of their code and implement similar logic; once the request is authenticated and ready to travel to the next stage, they use the account ID to delegate the operation to a Durable Object called Account Controller.
// env.ACCOUNTS is the Account Controllers Durable Objects namespace
const accountStubId = c.env.ACCOUNTS.idFromName(accountId.toString());
const accountStub = c.env.ACCOUNTS.get(accountStubId);
As you can see, every account has its own Account Controller Durable Object.
Account Controllers
The Account Controller is a dedicated persisted database that stores the list of all the account’s workflows, versions, and instances. We scale to millions of account controllers, one per every Cloudflare account using Workflows, by leveraging the power of Durable Objects with SQLite backend.
Durable Objects (DOs) are single-threaded singletons that run in our data centers and are bound to a stateful storage API, in this case, SQLite. They are also Workers, just a special kind, and have access to all of our other APIs. This makes it easy to build consistent, highly available distributed applications with them.
Here’s what we get for free by using one Durable Object per Workflows account:
Sharding based on account boundaries aligns perfectly with the way we manage resources at Cloudflare internally. Also, due to the nature of DOs, there are other things that this model gets us for free: Not that we expect them, but eventual bugs or state inconsistencies during beta are confined to the affected account, and don’t impact everyone.
DO instances run close to the end user; Alice is in London and will call the config API through our LHR data center, while Bob is in Lisbon and will connect to LIS.
Because every account is a Worker, we can gradually upgrade them to new versions, starting with the internal users, thus derisking real customers.
Before SQLite, our only option was to use the Durable Object’s key-value storage API, but having a relational database at our fingertips and being able to create tables and do complex queries is a significant enabler. For example, take a look at how we implement the internal method getWorkflow():
async function getWorkflow(accountId: number, workflowName: string) {
  try {
    const res = this.ctx.storage.transactionSync(() => {
      const cursor = Array.from(
        this.ctx.storage.sql.exec(
          `
                    SELECT *,
                    (SELECT class_name
                        FROM   versions
                        WHERE  workflow_id = w.id
                        ORDER  BY created_on DESC
                        LIMIT  1) AS class_name
                    FROM   workflows w
                    WHERE  w.name = ?
                    `,
          workflowName
        )
      )[0] as Workflow;

      return cursor;
    });

    this.sendAnalytics(accountId, begin, "getWorkflow");
    return res as Workflow | undefined;
  } catch (err) {
    this.sendErrorAnalytics(accountId, begin, "getWorkflow");
    throw err;
  }
}
The other thing we take advantage of in Workflows is using the recently announced JavaScript-native RPC feature when communicating between components.
Before RPC, we had to fetch() between components, make HTTP requests, and serialize and deserialize the parameters and the payload. Now, we can async call the remote object’s method as if it was local. Not only does this feel more natural and simplify our logic, but it’s also more efficient, and we can take advantage of TypeScript type-checking when writing code.
This is how the Configuration API would call the Account Controller’s countWorkflows() method before:
The other powerful feature of our RPC system is that it supports passing not only Structured Cloneable objects back and forth but also entire classes. More on this later.
Let’s move on to Engine.
Engine and instance
Every instance of a workflow runs alongside an Engine instance. The Engine is responsible for starting up the user’s workflow entry point, executing the steps on behalf of the user, handling their results, and tracking the workflow state until completion.
When we started thinking about the Engine, we thought about modeling it after a state machine, and that was what our initial prototypes looked like. However, state machines require an ahead-of-time understanding of the userland code, which implies having a build step before running them. This is costly at scale and introduces additional complexity.
A few iterations later, we had another idea. What if we could model the engine as a game loop?
Unlike other computer programs, games operate regardless of a user’s input. The game loop is essentially a sequence of tasks that implement the game’s logic and update the display, typically one loop per video frame. Here’s an example of a game loop in pseudo-code:
while (game in running)
    check for user input
    move graphics
    play sounds
end while
Well, an oversimplified version of our Workflow engine would look like this:
while (last step not completed)
    iterate every step
       use memoized cache as response if the step has run already
       continue running step or timer if it hasn't finished yet
end while
A workflow is indeed a loop that keeps on going, performing the same sequence of logical tasks until the last step completes.
The Engine and the instance run hand-in-hand in a one-to-one relationship. The first is managed, and part of the platform. It uses SQLite and other platform APIs internally, and we can constantly add new features, fix bugs, and deploy new versions, while keeping everything transparent to the end user. The second is the actual account-owned Worker script that declares the Workflow steps.
For example, when someone passes a callback into step.do():
We switch execution over to the Engine. Again, this is possible because of the power of JS RPC. Besides passing Structured Cloneable objects back and forth, JS RPC allows us to create and pass entire application-defined classes that extend the built-in RpcTarget. So this is what happens behind the scenes when your Instance calls step.do() (simplified):
export class Context extends RpcTarget {

  async do<T>(name: string, callback: () => Promise<T>): Promise<T> {

    // First we check we have a cache of this step.do() already
    const maybeResult = await this.#state.storage.get(name);

    // We return the cache if it exists
    if (maybeValue) { return maybeValue; }

    // Else we run the user callback
    return doWrapper(callback);
  }

}
Here’s a more complete diagram of the Engine’s step.do() lifecycle:
Again, this diagram only partially represents everything we do in the Engine; things like logging for observability or handling exceptions are missing, and we don’t get into the details of how queuing is implemented. However, it gives you a good idea of how the Engine abstracts and handles all the complexities of completing a step under the hood, allowing us to expose a simple-to-use API to end users.
Also, it’s worth reiterating that every workflow instance is an Engine behind the scenes, and every Engine is an SQLite-backed Durable Object. This ensures that every instance runtime and state are isolated and independent of each other and that we can effortlessly scale to run billions of workflow instances, a solved problem for Durable Objects.
Durability
Durable Execution is all the rage now when we talk about workflow engines, and ours is no exception. Workflows are typically long-lived processes that run multiple functions in sequence where anything can happen. Those functions can time out or fail because of a remote server error or a network issue and need to be retried. A workflow engine ensures that your application runs smoothly and completes regardless of the problems it encounters.
Durability means that if and when a workflow fails, the Engine can re-run it, resume from the last recorded step, and deterministically re-calculate the state from all the successful steps’ cached responses. This is possible because steps are stateful and idempotent; they produce the same result no matter how many times we run them, thus not causing unintended duplicate effects like sending the same invoice to a customer multiple times.
We ensure durability and handle failures and retries by sharing the same technique we use for a step.sleep() that requires sleeping for days or months: a combination of using scheduler.wait(), a method of the upcoming WICG Scheduling API that we already support, and Durable Objects alarms, which allow you to schedule the Durable Object to be woken up at a time in the future.
These two APIs allow us to overcome the lack of guarantees that a Durable Object runs forever, giving us complete control of its lifecycle. Since every state transition through userland code persists in the Engine’s strongly consistent SQLite, we track timestamps when a step begins execution, its attempts (if it needs retries), and its completion.
This means that steps pending if a Durable Object is evicted — perhaps due to a two-month-long timer — get rerun on the next lifetime of the Engine (with its cache from the previous lifetime hydrated) that is triggered by an alarm set with the timestamp of the next expected state transition.
Real-life workflow, step by step
Let’s walk through an example of a real-life application. You run an e-commerce website and would like to send email reminders to your customers for forgotten carts that haven’t been checked out in a few days.
What would typically have to be a combination of a queue, a cron job, and querying a database table periodically can now simply be a Workflow that we start on every new cart:
import {
  WorkflowEntrypoint,
  WorkflowEvent,
  WorkflowStep,
} from "cloudflare:workers";
import { sendEmail } from "./legacy-email-provider";

type Params = {
  cartId: string;
};

type Env = {
  DB: D1Database;
};

export class Purchase extends WorkflowEntrypoint<Env, Params> {
  async run(
    event: WorkflowEvent<Params>,
    step: WorkflowStep
  ): Promise<unknown> {
    await step.sleep("wait for three days", "3 days");

    // Retrieve cart from D1
    const cart = await step.do("retrieve cart from database", async () => {
      const { results } = await this.env.DB.prepare(`SELECT * FROM cart WHERE id = ?`)
        .bind(event.payload.cartId)
        .all();
      return results[0];
    });

    if (!cart.checkedOut) {
      await step.do("send an email", async () => {
        await sendEmail("reminder", cart);
      });
    }
  }
}
This works great. However, sometimes the sendEmail function fails due to an upstream provider erroring out. While step.do automatically retries with a reasonable default configuration, we can define our settings:
The HTTP API makes it easy to trigger new instances of workflows from any system, even if it isn’t on Cloudflare, or from the command line. For example:
Wrangler goes one step further and gives us a friendlier set of commands to interact with workflows with fancy formatted outputs without needing to authenticate with tokens. Type npx wrangler workflows for help, or:
Furthermore, Workflows has first-party support in wrangler, and you can test your instances locally. A Workflow is similar to a regular WorkerEntrypoint in your Worker, which means that wrangler dev just naturally works.
❯ npx wrangler dev

 ⛅️ wrangler 3.82.0
----------------------------

Your worker has access to the following bindings:
- Workflows:
  - CART_WORKFLOW: EcommerceCartWorkflow
⎔ Starting local server...
[wrangler:inf] Ready on http://localhost:8787
╭───────────────────────────────────────────────╮
│  [b] open a browser, [d] open devtools        │
╰───────────────────────────────────────────────╯
Workflow APIs are also available as a Worker binding. You can interact with the platform programmatically from another Worker script in the same account without worrying about permissions or authentication. You can even have workflows that call and interact with other workflows.
import { WorkerEntrypoint } from "cloudflare:workers";

type Env = { DEMO_WORKFLOW: Workflow };
export default class extends WorkerEntrypoint<Env> {
  async fetch() {
    // Pass in a user defined name for this instance
    // In this case, we use the same as the cartId
    const instance = await this.env.DEMO_WORKFLOW.create({
      id: "f3bcc11b-2833-41fb-847f-1b19469139d1",
      params: {
          cartId: "f3bcc11b-2833-41fb-847f-1b19469139d1",
      }
    });
  }
  async scheduled() {
    // Restart errored out instances in a cron
    const instance = await this.env.DEMO_WORKFLOW.get(
      "f3bcc11b-2833-41fb-847f-1b19469139d1"
    );
    const status = await instance.status();
    if (status.error) {
      await instance.restart();
    }
  }
}
Observability
Having good observability and data on often long-lived asynchronous tasks is crucial to understanding how we’re doing under normal operation and, more importantly, when things go south, and we need to troubleshoot problems or when we are iterating on code changes.
We designed Workflows around the philosophy that there is no such thing as too much logging. You can get all the SQLite data for your workflow and its instances by calling the REST APIs. Here is the output of an instance:
As you can see, this is essentially a dump of the instance engine SQLite in JSON. You have the errors, messages, current status, and what happened with every step, all time stamped to the millisecond.
It’s one thing to get data about a specific workflow instance, but it’s another to zoom out and look at aggregated statistics of all your workflows and instances over time. Workflows data is available through our GraphQL Analytics API, so you can query it in aggregate and generate valuable insights and reports. In this example we ask for aggregated analytics about the wall time of all the instances of the “e-commerce-carts” workflow:
For convenience, you can evidently also use Wrangler to describe a workflow or an instance and get an instant and beautifully formatted response:
sid ~ npx wrangler workflows instances describe purchase-workflow latest

 ⛅️ wrangler 3.80.4

Workflow Name:         purchase-workflow
Instance Id:           d4280218-7756-41d2-bccd-8d647b82d7ce
Version Id:            0c07dbc4-aaf3-44a9-9fd0-29437ed11ff6
Status:                ✅ Completed
Trigger:               🌎 API
Queued:                14/10/2024, 16:25:17
Success:               ✅ Yes
Start:                 14/10/2024, 16:25:17
End:                   14/10/2024, 16:26:17
Duration:              1 minute
Last Successful Step:  wait for three days
Output:                false
Steps:

  Name:      wait for three days
  Type:      💤 Sleeping
  Start:     14/10/2024, 16:25:17
  End:       17/10/2024, 16:25:17
  Duration:  3 day
And finally, we worked really hard to get you the best dashboard UI experience when navigating Workflows data.
So, how much does it cost?
It’d be painful if we introduced a powerful new way to build Workers applications but made it cost prohibitive.
Workflows is priced just like Cloudflare Workers, where we introduced CPU-based pricing: only on active CPU time and requests, not duration (aka: wall time).
Workers Standard pricing model
This is especially advantageous when building the long-running, multi-step applications that Workflows enables: if you had to pay while your Workflow was sleeping, waiting on an event, or making a network call to an API, writing the “right” code would be at odds with writing affordable code.
There’s also no need to keep a Kubernetes cluster or a group of virtual machines running (and burning a hole in your wallet): we manage the infrastructure, and you only pay for the compute your Workflows consume.
What’s next?
Today, after months of developing the platform, we are announcing the open beta program, and we couldn’t be more excited to see how you will be using Workflows. Looking forward, we want to do things like triggering instances from queue messages and have other ideas, but at the same time, we are certain that your feedback will help us shape the roadmap ahead.
We hope that this blog post gets you thinking about how to use Workflows for your next application, but also that it inspires you on what you can build on top of Workers. Workflows as a platform is entirely built on top of Workers, its resources, and APIs. Anyone can do it, too.
Cloudflare Queues let a developer decouple their Workers into event-driven services. Producer Workers write events to a Queue, and consumer Workers are invoked to take actions on the events. For example, you can use a Queue to decouple an e-commerce website from a service which sends purchase confirmation emails to users. During 2024’s Birthday Week, we announced that Cloudflare Queues is now Generally Available, with significant performance improvements that enable larger workloads. To accomplish this, we switched to a new architecture for Queues that enabled the following improvements:
Median latency for sending messages has dropped from ~200ms to ~60ms
Maximum throughput for each Queue has increased over 10x, from 400 to 5000 messages per second
Maximum Consumer concurrency for each Queue has increased from 20 to 250 concurrent invocations
Median latency drops from ~200ms to ~60ms as Queues are migrated to the new architecture
In this blog post, we’ll share details about how we built Queues using Durable Objects and the Cloudflare Developer Platform, and how we migrated from an initial Beta architecture to a geographically-distributed, horizontally-scalable architecture for General Availability.
v1 Beta architecture
When initially designing Cloudflare Queues, we decided to build something simple that we could get into users’ hands quickly. First, we considered leveraging an off-the-shelf messaging system such as Kafka or Pulsar. However, we decided that it would be too challenging to operate these systems at scale with the large number of isolated tenants that we wanted to support.
Instead of investing in new infrastructure, we decided to build on top of one of Cloudflare’s existing developer platform building blocks: Durable Objects.Durable Objects are a simple, yet powerful building block for coordination and storage in a distributed system. In our initial v1 architecture, each Queue was implemented using a single Durable Object. As shown below, clients would send messages to a Worker running in their region, which would be forwarded to the single Durable Object hosted in the WNAM (Western North America) region. We used a single Durable Object for simplicity, and hosted it in WNAM for proximity to our centralized configuration API service.
One of a Queue’s main responsibilities is to accept and store incoming messages. Sending a message to a v1 Queue used the following flow:
A client sends a POST request containing the message body to the Queues API at /accounts/:accountID/queues/:queueID/messages
The request is handled by an instance of the Queue Broker Worker in a Cloudflare data center running near the client.
The Worker performs authentication, and then uses Durable Objects idFromName API to route the request to the Queue Durable Object for the given queueID
The Queue Durable Object persists the message to storage before returning a success back to the client.
Durable Objects handled most of the heavy-lifting here: we did not need to set up any new servers, storage, or service discovery infrastructure. To route requests, we simply provided a queueID and the platform handled the rest. To store messages, we used the Durable Object storage API to put each message, and the platform handled reliably storing the data redundantly.
Consuming messages
The other main responsibility of a Queue is to deliver messages to a Consumer. Delivering messages in a v1 Queue used the following process:
Each Queue Durable Object maintained an alarm that was always set when there were undelivered messages in storage. The alarm guaranteed that the Durable Object would reliably wake up to deliver any messages in storage, even in the presence of failures. The alarm time was configured to fire after the user’s selected max wait time, if only a partial batch of messages was available. Whenever one or more full batches were available in storage, the alarm was scheduled to fire immediately.
The alarm would wake the Durable Object, which continually looked for batches of messages in storage to deliver.
Each batch of messages was sent to a “Dispatcher Worker” that used Workers for Platformsdynamic dispatch to pass the messages to the queue() function defined in a user’s Consumer Worker
This v1 architecture let us flesh out the initial version of the Queues Beta product and onboard users quickly. Using Durable Objects allowed us to focus on building application logic, instead of complex low-level systems challenges such as global routing and guaranteed durability for storage. Using a separate Durable Object for each Queue allowed us to host an essentially unlimited number of Queues, and provided isolation between them.
However, using only one Durable Object per queue had some significant limitations:
Latency: we created all of our v1 Queue Durable Objects in Western North America. Messages sent from distant regions incurred significant latency when traversing the globe.
Throughput: A single Durable Object is not scalable: it is single-threaded and has a fixed capacity for how many requests per second it can process. This is where the previous 400 messages per second limit came from.
Consumer Concurrency: Due to concurrent subrequest limits, a single Durable Object was limited in how many concurrent subrequests it could make to our Dispatcher Worker. This limited the number of queue() handler invocations that it could run simultaneously.
To solve these issues, we created a new v2 architecture that horizontally scales across multiple Durable Objects to implement each single high-performance Queue.
v2 Architecture
In the new v2 architecture for Queues, each Queue is implemented using multiple Durable Objects, instead of just one. Instead of a single region, we place Storage Shard Durable Objects in all available regions to enable lower latency. Within each region, we create multiple Storage Shards and load balance incoming requests amongst them. Just like that, we’ve multiplied message throughput.
Sending a message to a v2 Queue uses the following flow:
A client sends a POST request containing the message body to the Queues API at /accounts/:accountID/queues/:queueID/messages
The request is handled by an instance of the Queue Broker Worker running in a Cloudflare data center near the client.
The Worker:
Performs authentication
Reads from Workers KV to obtain a Shard Map that lists available storage shards for the given region and queueID
Picks one of the region’s Storage Shards at random, and uses Durable Objects idFromName API to route the request to the chosen shard
The Storage Shard persists the message to storage before returning a success back to the client.
In this v2 architecture, messages are stored in the closest available Durable Object storage cluster near the user, greatly reducing latency since messages don’t need to be shipped all the way to WNAM. Using multiple shards within each region removes the bottleneck of a single Durable Object, and allows us to scale each Queue horizontally to accept even more messages per second. Workers KV acts as a fast metadata store: our Worker can quickly look up the shard map to perform load balancing across shards.
To improve the Consumer side of v2 Queues, we used a similar “scale out” approach. A single Durable Object can only perform a limited number of concurrent subrequests. In v1 Queues, this limited the number of concurrent subrequests we could make to our Dispatcher Worker. To work around this, we created a new Consumer Shard Durable Object class that we can scale horizontally, enabling us to execute many more concurrent instances of our users’ queue() handlers.
Consumer Durable Objects in v2 Queues use the following approach:
Each Consumer maintains an alarm that guarantees it will wake up to process any pending messages. v2 Consumers are notified by the Queue’s Coordinator (introduced below) when there are messages ready for consumption. Upon notification, the Consumer sets an alarm to go off immediately.
The Consumer looks at the shard map, which contains information about the storage shards that exist for the Queue, including the number of available messages on each shard.
The Consumer picks a random storage shard with available messages, and asks for a batch.
The Consumer sends the batch to the Dispatcher Worker, just like for v1 Queues.
After processing the messages, the Consumer sends another request to the Storage Shard to either “acknowledge” or “retry” the messages.
This scale-out approach enabled us to work around the subrequest limits of a single Durable Object, and increase the maximum supported concurrency level of a Queue from 20 to 250.
The Coordinator and “Control Plane”
So far, we have primarily discussed the “Data Plane” of a v2 Queue: how messages are load balanced amongst Storage Shards, and how Consumer Shards read and deliver messages. The other main piece of a v2 Queue is the “Control Plane”, which handles creating and managing all the individual Durable Objects in the system. In our v2 architecture, each Queue has a single Coordinator Durable Object that acts as the brain of the Queue. Requests to create a Queue, or change its settings, are sent to the Queue’s Coordinator.
The Coordinator maintains a Shard Map for the Queue, which includes metadata about all the Durable Objects in the Queue (including their region, number of available messages, current estimated load, etc.). The Coordinator periodically writes a fresh copy of the Shard Map into Workers KV, as pictured in step 1 of the diagram. Placing the shard map into Workers KV ensures that it is globally cached and available for our Worker to read quickly, so that it can pick a shard to accept the message.
Every shard in the system periodically sends a heartbeat to the Coordinator as shown in steps 2 and 3 of the diagram. Both Storage Shards and Consumer Shards send heartbeats, including information like the number of messages stored locally, and the current load (requests per second) that the shard is handling. The Coordinator uses this information to perform autoscaling. When it detects that the shards in a particular region are overloaded, it creates additional shards in the region, and adds them to the shard map in Workers KV. Our Worker sees the updated shard map and naturally load balances messages across the freshly added shards. Similarly, the Coordinator looks at the backlog of available messages in the Queue, and decides to add more Consumer shards to increase Consumer throughput when the backlog is growing. Consumer Shards pull messages from Storage Shards for processing as shown in step 4 of the diagram.
Switching to a new scalable architecture allowed us to meet our performance goals and take Queues to GA. As a recap, this new architecture delivered these significant improvements:
P50 latency for writing to a Queue has dropped from ~200ms to ~60ms.
Maximum throughput for a Queue has increased from 400 to 5000 messages per second.
Maximum consumer concurrency has increased from 20 to 250 invocations.
What’s next for Queues
We plan on leveraging the performance improvements in the new beta version of Durable Objects which use SQLite to continue to improve throughput/latency in Queues.
We will soon be adding message management features to Queues so that you can take actions to purge messages in a queue, pause consumption of messages, or “redrive”/move messages from one queue to another (for example messages that have been sent to a Dead Letter Queue could be “redriven” or moved back to the original queue).
Work to make Queues the “event hub” for the Cloudflare Developer Platform:
Create a low-friction way for events emitted from other Cloudflare services with event schemas to be sent to Queues.
Build multi-Consumer support for Queues so that Queues are no longer limited to one Consumer per queue.
To start using Queues, head over to our Getting Started guide.
Do distributed systems like Cloudflare Queues and Durable Objects interest you? Would you like to help build them at Cloudflare? We’re Hiring!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.