Set up federated access to Amazon Athena for Microsoft AD FS users using AWS Lake Formation and a JDBC client

Post Syndicated from Mostafa Safipour original https://aws.amazon.com/blogs/big-data/set-up-federated-access-to-amazon-athena-for-microsoft-ad-fs-users-using-aws-lake-formation-and-a-jdbc-client/

Tens of thousands of AWS customers choose Amazon Simple Storage Service (Amazon S3) as their data lake to run big data analytics, interactive queries, high-performance computing, and artificial intelligence (AI) and machine learning (ML) applications to gain business insights from their data. On top of these data lakes, you can use AWS Lake Formation to ingest, clean, catalog, transform, and help secure your data and make it available for analysis and ML. Once you have setup your data lake, you can use Amazon Athena which is an interactive query service that makes it easy to analyze data in Amazon Simple Storage Service (Amazon S3) using standard SQL.

With Lake Formation, you can configure and manage fine-grained access control to new or existing databases, tables, and columns defined in the AWS Glue Data Catalog for data stored in Amazon S3. After you set access permissions using Lake Formation, you can use analytics services such as Amazon Athena, Amazon Redshift, and Amazon EMR without needing to configure policies for each service.

Many of our customers use Microsoft Active Directory Federation Services (AD FS) as their identity provider (IdP) while using cloud-based services. In this post, we provide a step-by-step walkthrough of configuring AD FS as the IdP for SAML-based authentication with Athena to query data stored in Amazon S3, with access permissions defined using Lake Formation. This enables end-users to log in to their SQL client using Active Directory credentials and access data with fine-grained access permissions.

Solution overview

To build the solution, we start by establishing trust between AD FS and your AWS account. With this trust in place, AD users can federate into AWS using their AD credentials and assume permissions of an AWS Identity and Access Management (IAM) role to access AWS resources such as the Athena API.

To create this trust, you add AD FS as a SAML provider into your AWS account and create an IAM role that federated users can assume. On the AD FS side, you add AWS as a relying party and write SAML claim rules to send the right user attributes to AWS (specifically Lake Formation) for authorization purposes.

The steps in this post are structured into the following sections:

  1. Set up an IAM SAML provider and role.
  2. Configure AD FS.
  3. Create Active Directory users and groups.
  4. Create a database and tables in the data lake.
  5. Set up the Lake Formation permission model.
  6. Set up a SQL client with JDBC connection.
  7. Verify access permissions.

The following diagram provides an overview of the solution architecture.

The flow for the federated authentication process is as follows:

  1. The SQL client which has been configured with Active Directory credentials sends an authentication request to AD FS.
  2. AD FS authenticates the user using Active Directory credentials, and returns a SAML assertion.
  3. The client makes a call to Lake Formation, which initiates an internal call with AWS Security Token Service (AWS STS) to assume a role with SAML for the client.
  4. Lake Formation returns temporary AWS credentials with permissions of the defined IAM role to the client.
  5. The client uses the temporary AWS credentials to call the Athena API StartQueryExecution.
  6. Athena retrieves the table and associated metadata from the AWS Glue Data Catalog.
  7. On behalf of the user, Athena requests access to the data from Lake Formation (GetDataAccess). Lake Formation assumes the IAM role associated with the data lake location and returns temporary credentials.
  8. Athena uses the temporary credentials to retrieve data objects from Amazon S3.
  9. Athena returns the results to the client based on the defined access permissions.

For our use case, we use two sample tables:

  • LINEORDER – A fact table containing orders
  • CUSTOMER – A dimension table containing customer information including Personally Identifiable Information (PII) columns (c_name, c_phone, c_address)

We also have data consumer users who are members of the following teams:

  • CustomerOps – Can see both orders and customer information, including PII attributes of the customer
  • Finance – Can see orders for analytics and aggregation purposes but only non-PII attributes of the customer

To demonstrate this use case, we create two users called CustomerOpsUser and FinanceUser and three AD groups for different access patterns: data-customer (customer information access excluding PII attributes), data-customer-pii (full customer information access including PII attributes), and data-order (order information access). By adding the users to these three groups, we can grant the right level of access to different tables and columns.

Prerequisites

To follow along with this walkthrough, you must meet the following prerequisites:

Set up an IAM SAML provider and role

To set up your SAML provider, complete the following steps:

  1. In the IAM console, choose Identity providers in the navigation pane.
  2. Choose Add provider.
  3. For Provider Type, choose SAML.
  4. For Provider Name, enter adfs-saml-provider.
  5. For Metadata Document, download your AD FS server’s federation XML file by entering the following address in a browser with access to the AD FS server:
    https://<adfs-server-name>/FederationMetadata/2007-06/FederationMetadata.xml

  6. Upload the file to AWS by choosing Choose file.
  7. Choose Add provider to finish.

Now you’re ready to create a new IAM role.

  1. In the navigation pane, choose Roles.
  2. Choose Create role.
  3. For the type of trusted entity, choose SAML 2.0 federation.
  4. For SAML provider, choose the provider you created (adfs-saml-provider).
  5. Choose Allow programmatic and AWS Management Console access.
  6. The Attribute and Value fields should automatically populate with SAML:aud and https://signin.aws.amazon.com/saml.
  7. Choose Next:Permissions.
  8. Add the necessary IAM permissions to this role. For this post, attach AthenaFullAccess.

If the Amazon S3 location for your Athena query results doesn’t start with aws-athena-query-results, add another policy to allow users write query results into your Amazon S3 location. For more information, see Specifying a Query Result Location Using the Athena Console and Writing IAM Policies: How to Grant Access to an Amazon S3 Bucket.

  1. Leave the defaults in the next steps and for Role name, enter adfs-data-access.
  2. Choose Create role.
  3. Take note of the SAML provider and IAM role names to use in later steps when creating the trust between the AWS account and AD FS.

Configure AD FS

SAML-based federation has two participant parties: the IdP (Active Directory) and the relying party (AWS), which is the service or application that wants to use authentication from the IdP.

To configure AD FS, you first add a relying party trust, then you configure SAML claim rules for the relying party. Claim rules are the way that AD FS forms a SAML assertion sent to a relying party. The SAML assertion states that the information about the AD user is true, and that it has authenticated the user.

Add a relying party trust

To create your relying party in AD FS, complete the following steps:

  1. Log in to the AD FS server.
  2. On the Start menu, open ServerManger.
  3. On the Tools menu, choose the AD FS Management console.
  4. Under Trust Relationships in the navigation pane, choose Relying Party Trusts.
  5. Choose Add Relying Party Trust.
  6. Choose Start.
  7. Select Import data about the relying party published online or on a local network and enter the URL https://signin.aws.amazon.com/static/saml-metadata.xml.
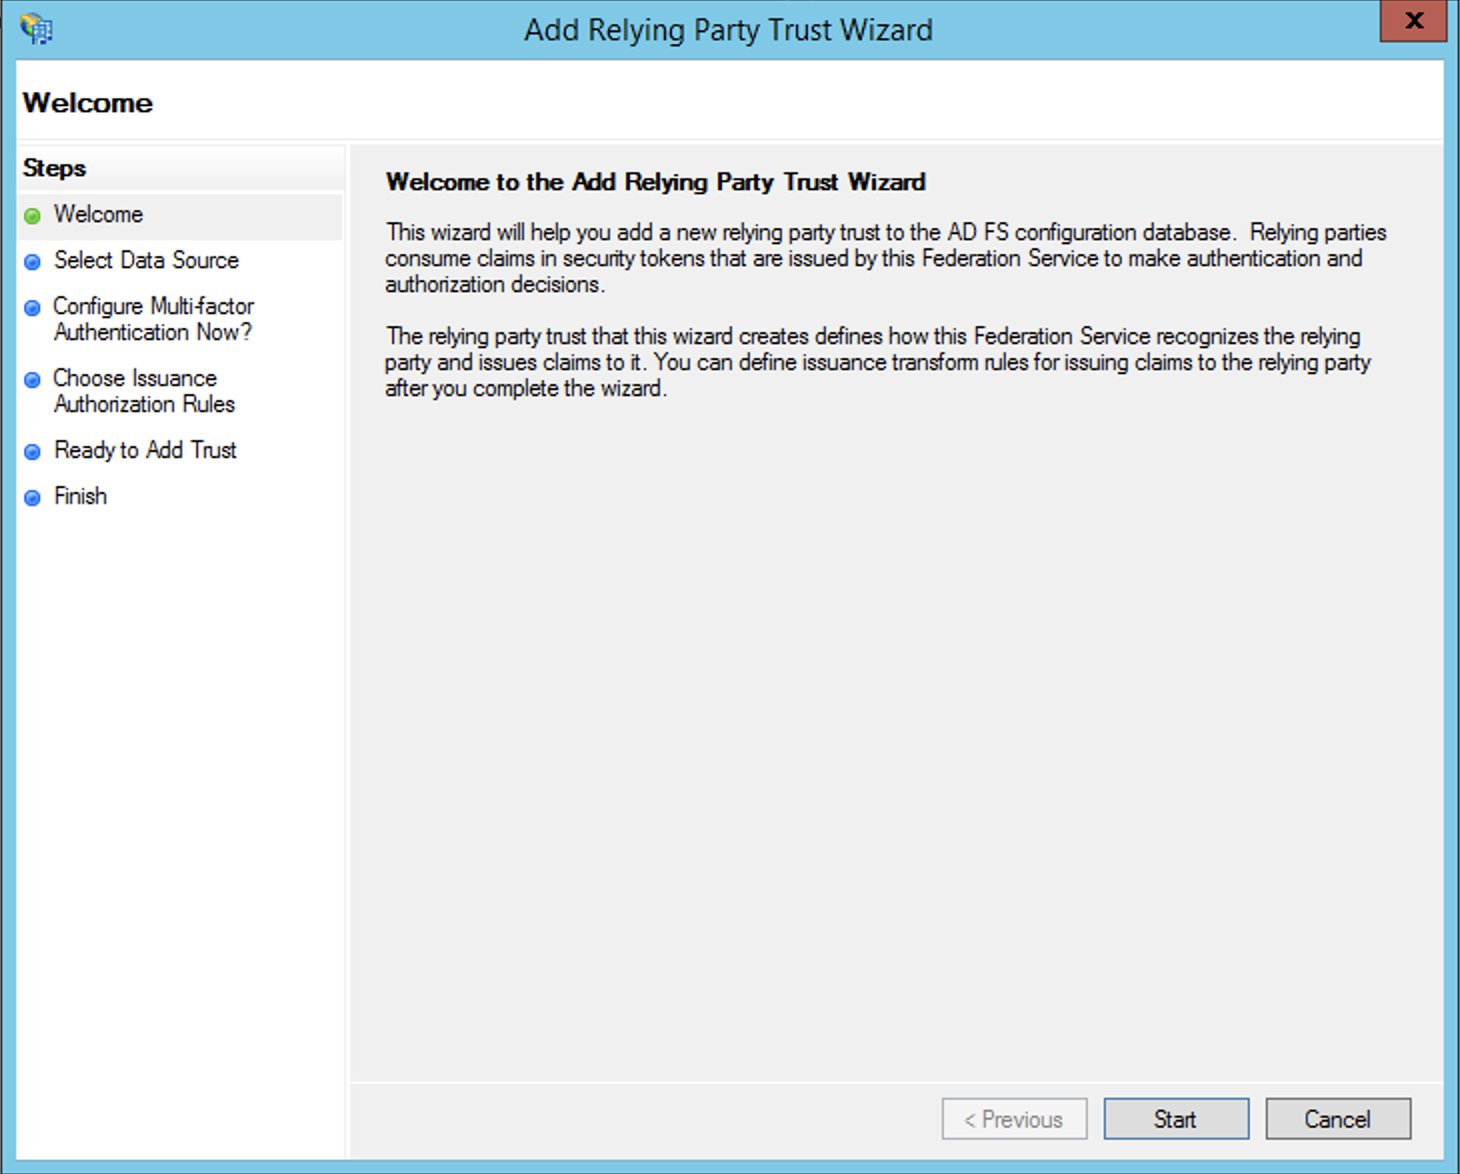
The metadata XML file is a standard SAML metadata document that describes AWS as a relying party.

  1. Choose Next.
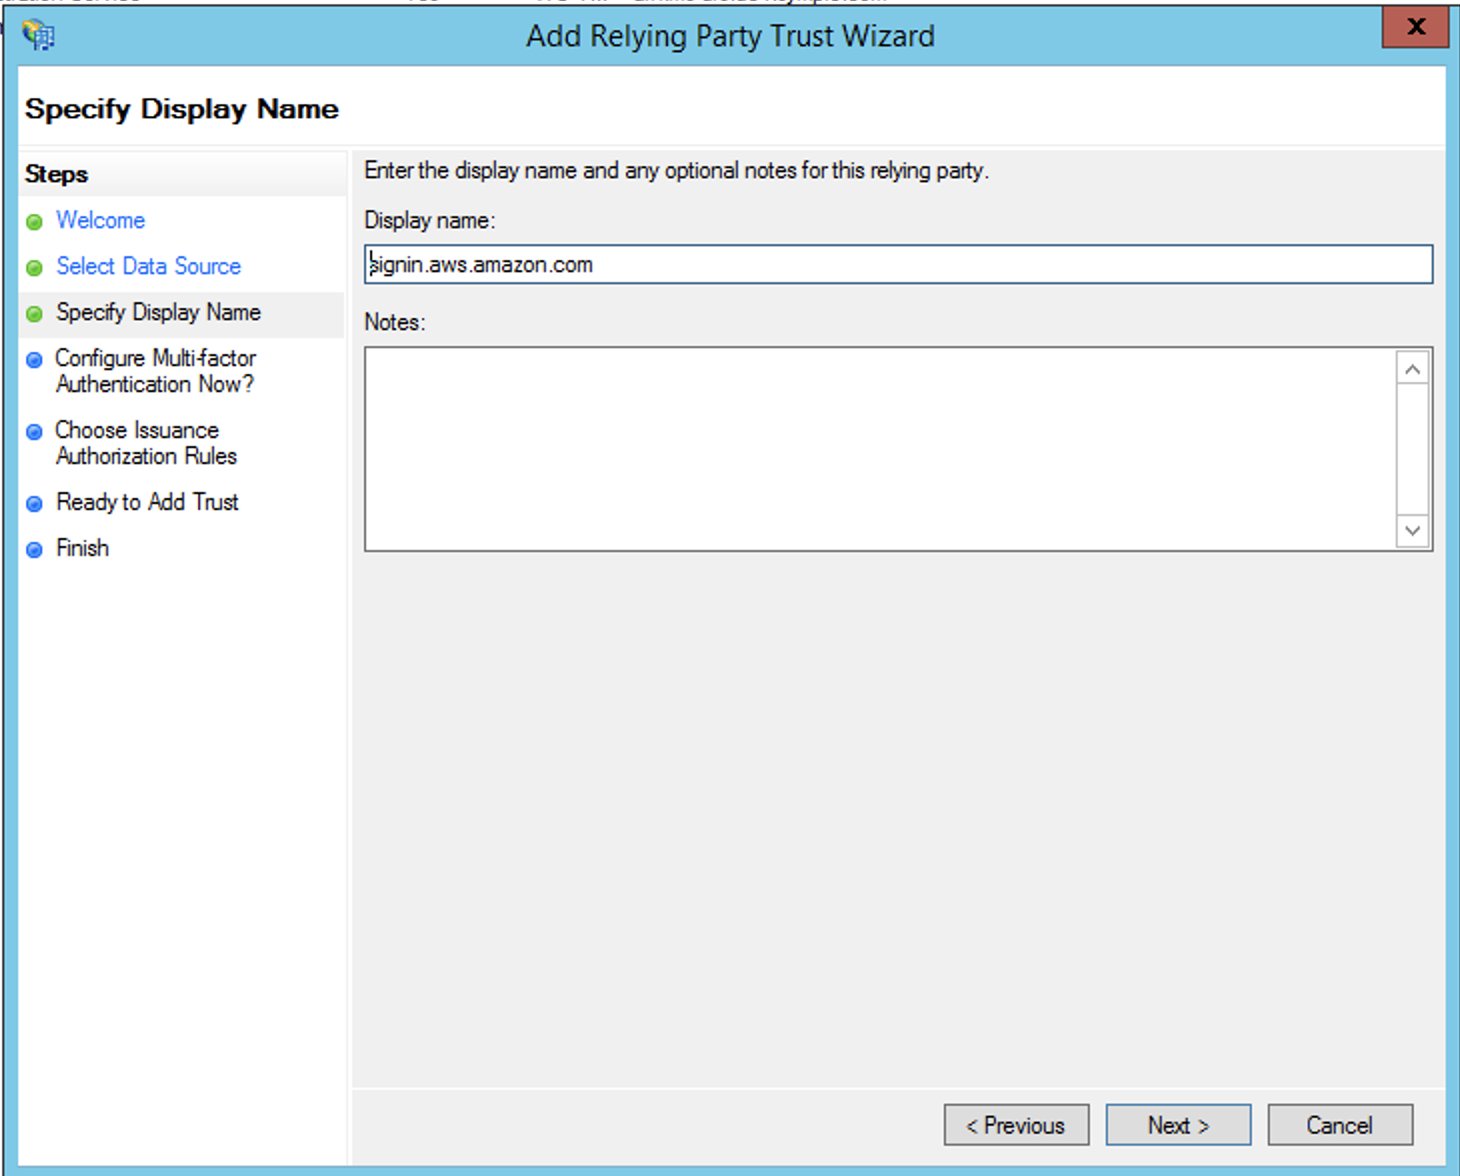
  2. For Display name, enter a name for your relying party.
  3. Choose Next.
  4. Select I do not want to configure multi-factor authentication.

For increased security, we recommend that you configure multi-factor authentication to help protect your AWS resources. We don’t enable multi-factor authentication for this post because we’re using a sample dataset.

  1. Choose Next.
  2. Select Permit all users to access this relying party and choose Next.

This allows all users in Active Directory to use AD FS with AWS as a relying party. You should consider your security requirements and adjust this configuration accordingly.

  1. Finish creating your relying party.

Configure SAML claim rules for the relying party

You create two sets of claim rules in this post. The first set (rules 1–4) contains AD FS claim rules that are required to assume an IAM role based on AD group membership. These are the rules that you also create if you want to establish federated access to the AWS Management Console. The second set (rules 5–6) are claim rules that are required for Lake Formation fine-grained access control.

To create AD FS claim rules, complete the following steps:

  1. On the AD FS Management console, find the relying party you created in the previous step.
  2. Right-click the relying party and choose Edit Claim Rules.
  3. Choose Add Rule and create your six new rules.
  4. Create claim rule 1, called NameID:
    1. For Rule template, use Transform an Incoming Claim.
    2. For Incoming claim type, choose Windows account name.
    3. For Outgoing claim type, choose Name ID.
    4. For Outgoing name ID format, choose Persistent Identifier.
    5. Select Pass through all claim values.
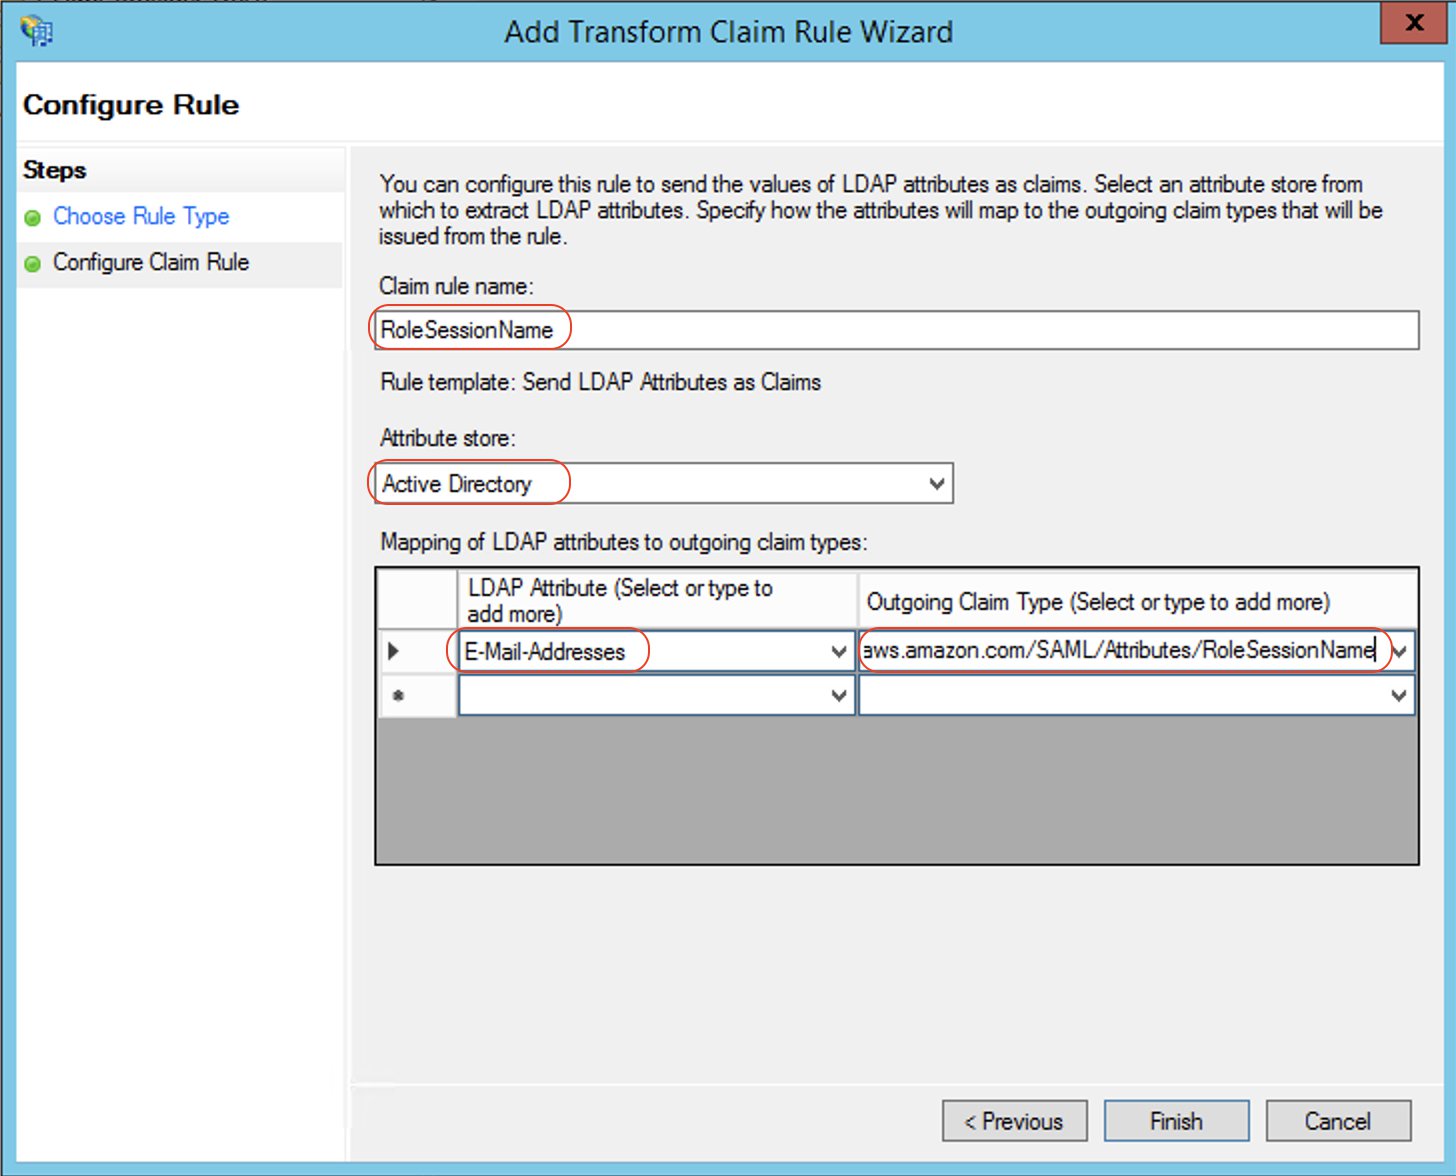
  5. Create claim rule 2, called RoleSessionName:
    1. For Rule template, use Send LDAP Attribute as Claims.
    2. For Attribute store, choose Active Directory.
    3. For Mapping of LDAP attributes to outgoing claim types, add the attribute E-Mail-Addresses and outgoing claim type https://aws.amazon.com/SAML/Attributes/RoleSessionName.
  6. Create claim rule 3, called Get AD Groups:
    1. For Rule template, use Send Claims Using a Custom Rule.
    2. For Custom rule, enter the following code:
      c:[Type == "http://schemas.microsoft.com/ws/2008/06/identity/claims/windowsaccountname", Issuer == "AD AUTHORITY"]
      => add(store = "Active Directory", types = ("http://temp/variable"), query = ";tokenGroups;{0}", param = c.Value);

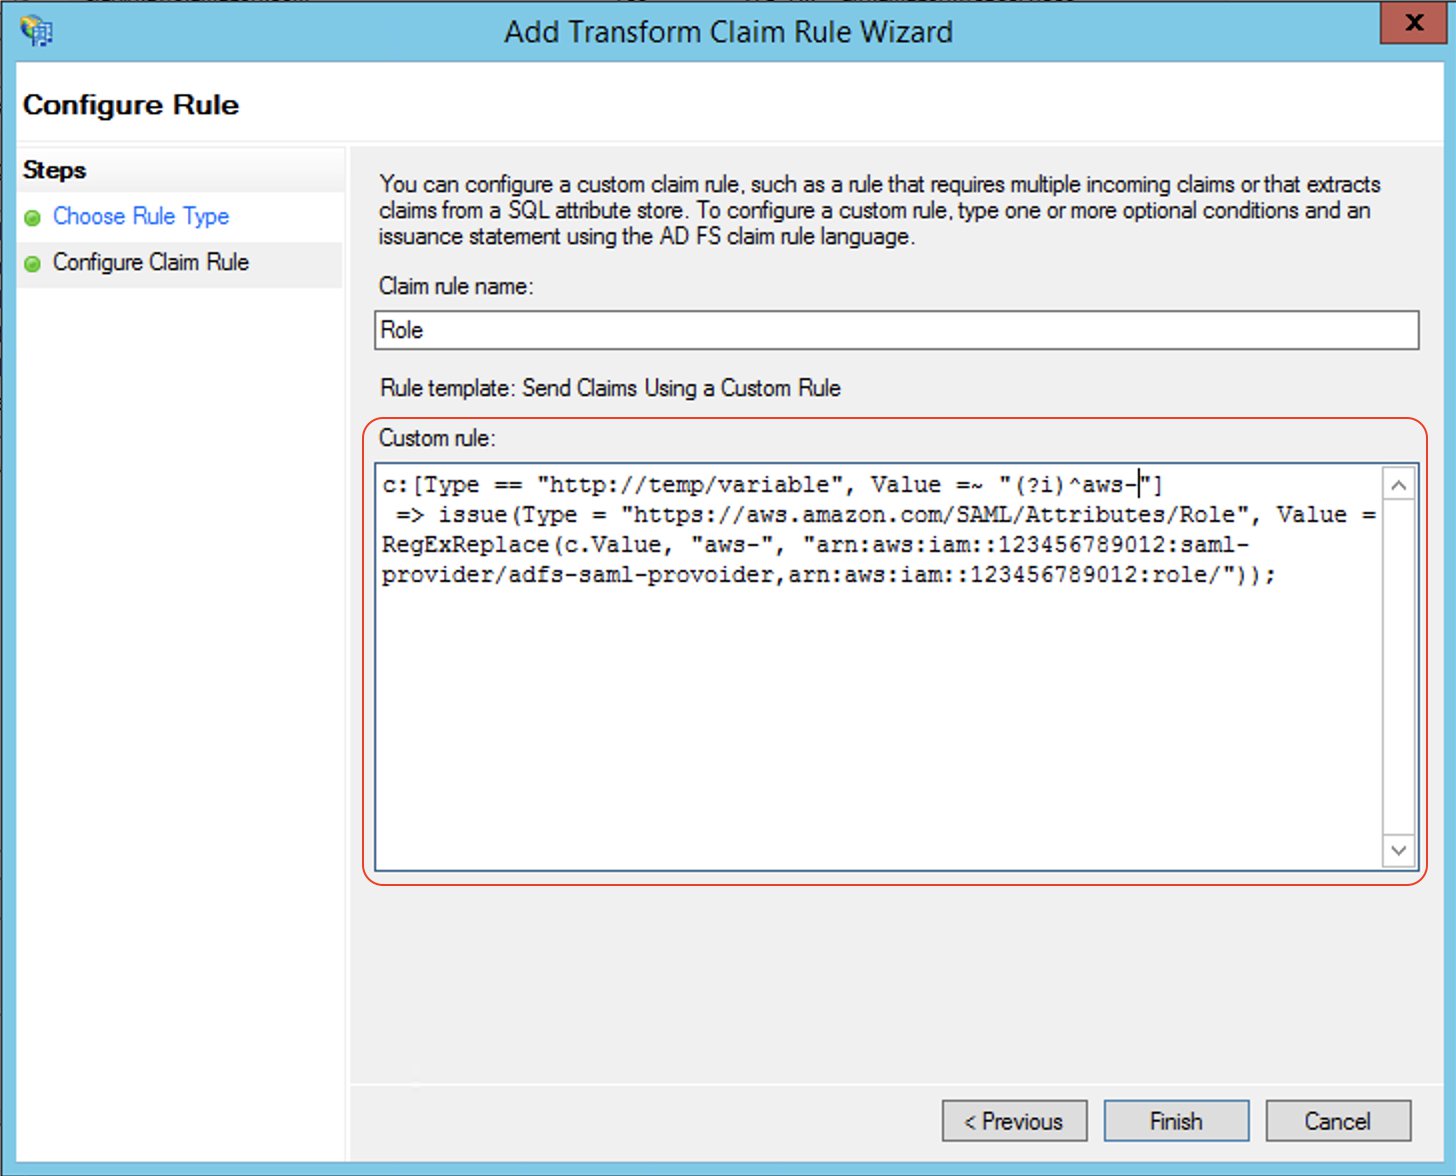
  7. Create claim rule 4, called Roles:
    1. For Rule template, use Send Claims Using a Custom Rule.
    2. For Custom rule, enter the following code (enter your account number and name of the SAML provider you created earlier):
      c:[Type == "http://temp/variable", Value =~ "(?i)^aws-"]
      => issue(Type = "https://aws.amazon.com/SAML/Attributes/Role", Value = RegExReplace(c.Value, "aws-", "arn:aws:iam::<AWS ACCOUNT NUMBER>:saml-provider/<adfs-saml-provider>,arn:aws:iam::<AWS ACCOUNT NUMBER>:role/"));

Claim rules 5 and 6 allow Lake Formation to make authorization decisions based on user name or the AD group membership of the user.

  1. Create claim rule 5, called LF-UserName, which passes the user name and SAML assertion to Lake Formation:
    1. For Rule template, use Send LDAP Attributes as Claims.
    2. For Attribute store, choose Active Directory.
    3. For Mapping of LDAP attributes to outgoing claim types, add the attribute User-Principal-Name and outgoing claim type https://lakeformation.amazon.com/SAML/Attributes/Username.
  2. Create claim rule 6, called LF-Groups, which passes data and analytics-related AD groups that the user is a member of, along with the SAML assertion to Lake Formation:
    1. For Rule template, use Send Claims Using a Custom Rule.
    2. For Custom rule, enter the following code:
      c:[Type == "http://temp/variable", Value =~ "(?i)^data-"]
      => issue(Type = "https://lakeformation.amazon.com/SAML/Attributes/Groups", Value = c.Value);

The preceding rule snippet filters AD group names starting with data-. This is an arbitrary naming convention; you can adopt your preferred naming convention for AD groups that are related to data lake access.

Create Active Directory users and groups

In this section, we create two AD users and required AD groups to demonstrate varying levels of access to the data.

Create users

You create two AD users: FinanceUser and CustomerOpsUser. Each user corresponds to an individual who is a member of the Finance or Customer business units. The following table summarizes the details of each user.


FinanceUser CustomerOpsUser
First Name FinanceUser CustomerOpsUser
User logon name [email protected] [email protected]
Email [email protected] [email protected]

To create your users, complete the following steps:

  1. On the Server Manager Dashboard, on the Tools menu, choose Active Directory Users and Computers.
  2. In the navigation pane, choose Users.
  3. On the tool bar, choose the Create user icon.
  4. For First name, enter FinanceUser.
  5. For Full name, enter FinanceUser.
  6. For User logon name, enter [email protected].
  7. Choose Next.
  8. Enter a password and deselect User must change password at next logon.

We choose this option for simplicity, but in real-world scenarios, newly created users must change their password for security reasons.

  1. Choose Next.
  2. In Active Directory Users and Computers, choose the user name.
  3. For Email, enter [email protected].

Adding an email is mandatory because it’s used as the RoleSessionName value in the SAML assertion.

  1. Choose OK.
  2. Repeat these steps to create CustomerOpsUser.

Create AD groups to represent data access patterns

Create the following AD groups to represent three different access patterns and also the ability to assume an IAM role:

  • data-customer – Members have access to non-PII columns of the customer table
  • data-customer-pii – Members have access to all columns of the customer table, including PII columns
  • data-order – Members have access to the lineorder table
  • aws-adfs-data-access – Members assume the adfs-data-access IAM role when logging in to AWS

To create the groups, complete the following steps:

  1. On the Server Manager Dashboard, on the Tools menu, choose Active Directory Users and Computers.
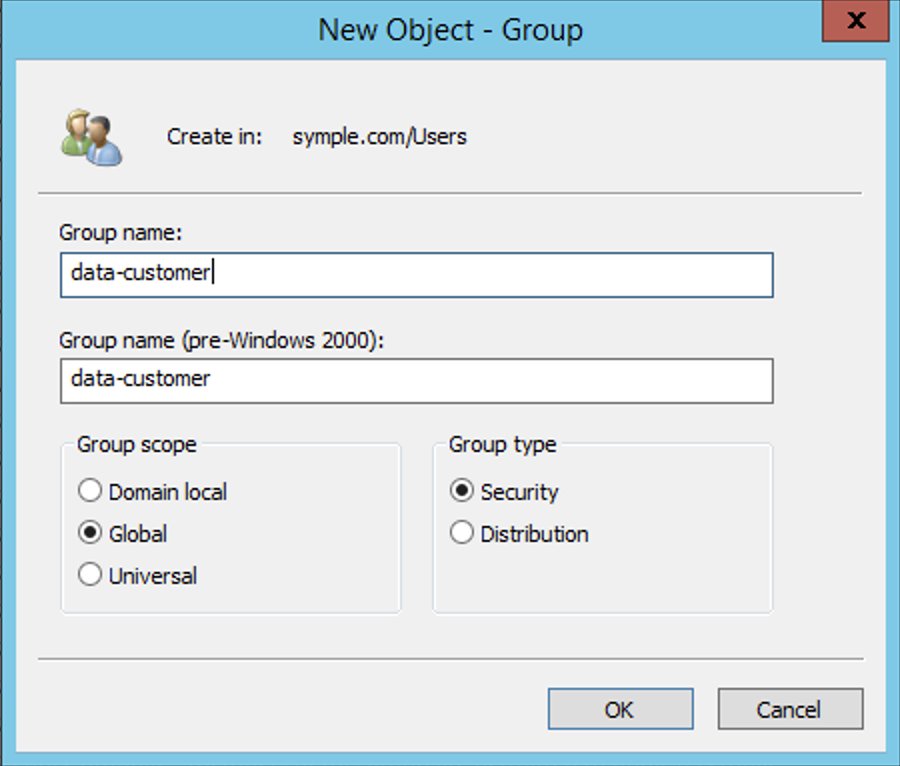
  2. On the tool bar, choose the Create new group icon.
  3. For Group name¸ enter data-customer.
  4. For Group scope, select Global.
  5. For Group type¸ select Security.
  6. Choose OK.
  7. Repeat these steps to create the remaining groups.
Add users to appropriate groups

Now you add your newly created users to their appropriate groups, as detailed in the following table.

User Group Membership Description
CustomerOpsUser data-customer-pii
data-order
aws-adfs-data-access
Sees all customer information including PII and their orders
FinanceUser data-customer
data-order
aws-adfs-data-access
Sees only non-PII customer data and orders

Complete the following steps:

  1. On the Server Manager Dashboard, on the Tools menu, choose Active Directory Users and Computers.
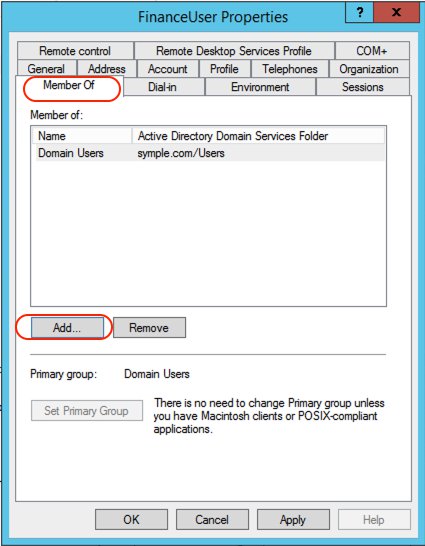
  2. Choose the user FinanceUser.
  3. On the Member Of tab, choose Add.
  4. Add the appropriate groups.
  5. Repeat these steps for CustomerOpsUser.
Create a database and tables in the data lake

In this step, you copy data files to an S3 bucket in your AWS account by running the following AWS Command Line Interface (AWS CLI) commands. For more information on how to set up the AWS CLI, refer to Configuration Basics.

These commands copy the files that contain data for customer and lineorder tables. Replace <BUCKET NAME> with the name of an S3 bucket in your AWS account.

aws s3 sync s3://awssampledb/load/ s3://<BUCKET NAME>/customer/ \
--exclude "*" --include "customer-fw.tbl-00*" --exclude "*.bak"

aws s3api copy-object --copy-source awssampledb/load/lo/lineorder-single.tbl000.gz \
--key lineorder/lineorder-single.tbl000.gz --bucket <BUCKET NAME> \
--tagging-directive REPLACE

For this post, we use the default settings for storing data and logging access requests within Amazon S3. You can enhance the security of your sensitive data with the following methods:

  • Implement encryption at rest using AWS Key Management Service (AWS KMS) and customer managed encryption keys
  • Use AWS CloudTrail and audit logging
  • Restrict access to AWS resources based on the least privilege principle

Additionally, Lake Formation is integrated with CloudTrail, a service that provides a record of actions taken by a user, role, or AWS service in Lake Formation. CloudTrail captures all Lake Formation API calls as events and is enabled by default when you create a new AWS account. When activity occurs in Lake Formation, that activity is recorded as a CloudTrail event along with other AWS service events in event history. For audit and access monitoring purposes, all federated user logins are logged via CloudTrail under the AssumeRoleWithSAML event name. You can also view specific user activity based on their user name in CloudTrail.

To create a database and tables in the Data Catalog, open the query editor on the Athena console and enter the following DDL statements. Replace <BUCKET NAME> with the name of the S3 bucket in your account.

CREATE DATABASE salesdata;
CREATE EXTERNAL TABLE salesdata.customer
(
    c_custkey VARCHAR(10),
    c_name VARCHAR(25),
    c_address VARCHAR(25),
    c_city VARCHAR(10),
    c_nation VARCHAR(15),
    c_region VARCHAR(12),
    c_phone VARCHAR(15),
    c_mktsegment VARCHAR(10)
)
-- The data files contain fixed width columns hence using RegExSerDe
ROW FORMAT SERDE 'org.apache.hadoop.hive.serde2.RegexSerDe'
WITH SERDEPROPERTIES (
    "input.regex" = "(.{10})(.{25})(.{25})(.{10})(.{15})(.{12})(.{15})(.{10})"
)
LOCATION 's3://<BUCKET NAME>/customer/';

CREATE EXTERNAL TABLE salesdata.lineorder(
  `lo_orderkey` int, 
  `lo_linenumber` int, 
  `lo_custkey` int, 
  `lo_partkey` int, 
  `lo_suppkey` int, 
  `lo_orderdate` int, 
  `lo_orderpriority` varchar(15), 
  `lo_shippriority` varchar(1), 
  `lo_quantity` int, 
  `lo_extendedprice` int, 
  `lo_ordertotalprice` int, 
  `lo_discount` int, 
  `lo_revenue` int, 
  `lo_supplycost` int, 
  `lo_tax` int, 
  `lo_commitdate` int, 
  `lo_shipmode` varchar(10))
ROW FORMAT DELIMITED 
  FIELDS TERMINATED BY '|' 
LOCATION 's3://<BUCKET NAME>/lineorder/';

Verify that tables are created and you can see the data:

SELECT * FROM "salesdata"."customer" limit 10;
SELECT * FROM "salesdata"."lineorder" limit 10;

Set up the Lake Formation permission model

Lake Formation uses a combination of Lake Formation permissions and IAM permissions to achieve fine-grained access control. The recommended approach includes the following:

  • Coarse-grained IAM permissions – These apply to the IAM role that users assume when running queries in Athena. IAM permissions control access to Lake Formation, AWS Glue, and Athena APIs.
  • Fine-grained Lake Formation grants – These control access to Data Catalog resources, Amazon S3 locations, and the underlying data at those locations. With these grants, you can give access to specific tables or only columns that contain specific data values.

Configure IAM role permissions

Earlier in the walkthrough, you created the IAM role adfs-data-access and attached the AWS managed IAM policy AthenaFullAccess to it. This policy has all the permissions required for the purposes of this post.

For more information, see the Data Analyst Permissions section in Lake Formation Personas and IAM Permissions Reference.

Register an S3 bucket as a data lake location

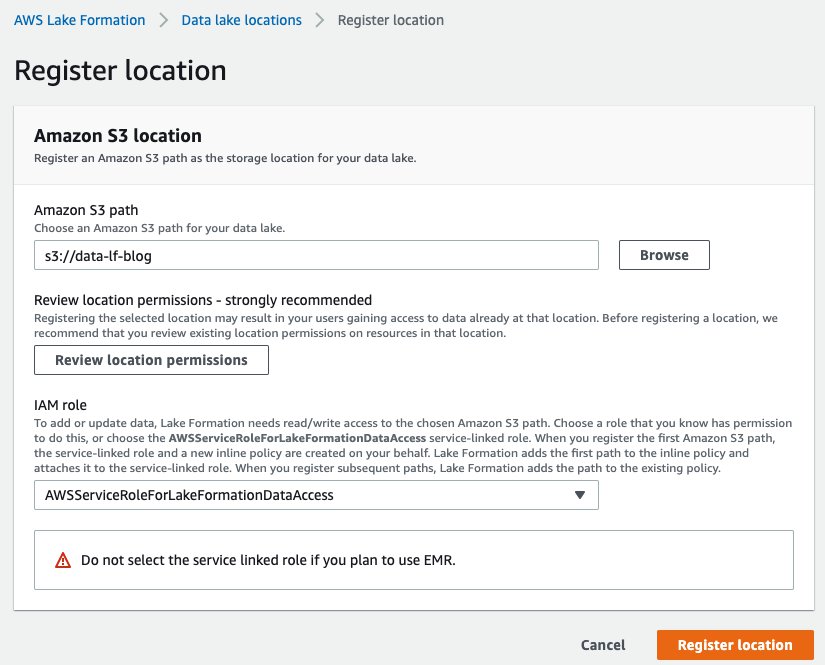
The mechanism to govern access to an Amazon S3 location using Lake Formation is to register a data lake location. Complete the following steps:

  1. On the Lake Formation console, choose Data lake locations.
  2. Choose Register location.
  3. For Amazon S3 path, choose Browse and locate your bucket.
  4. For IAM role, choose AWSServiceRoleForLakeFormationDataAccess.

In this step, you specify an IAM service-linked role, which Lake Formation assumes when it grants temporary credentials to integrated AWS services that access the data in this location. This role and its permissions are managed by Lake Formation and can’t be changed by IAM principals.

  1. Choose Register location.

Configure data permissions

Now that you have registered the Amazon S3 path, you can give AD groups appropriate permissions to access tables and columns in the salesdata database. The following table summarizes the new permissions.

Database and Table AD Group Name Table Permissions Data Permissions
salesdata.customer data-customer Select c_city, c_custkey, c_mktsegment, c_nation, and c_region
salesdata.customer data-customer-pii Select All data access
salesdata.lineorder data-order Select All data access
  1. On the Lake Formation console, choose Tables in the navigation pane.
  2. Filter tables by the salesdata database.
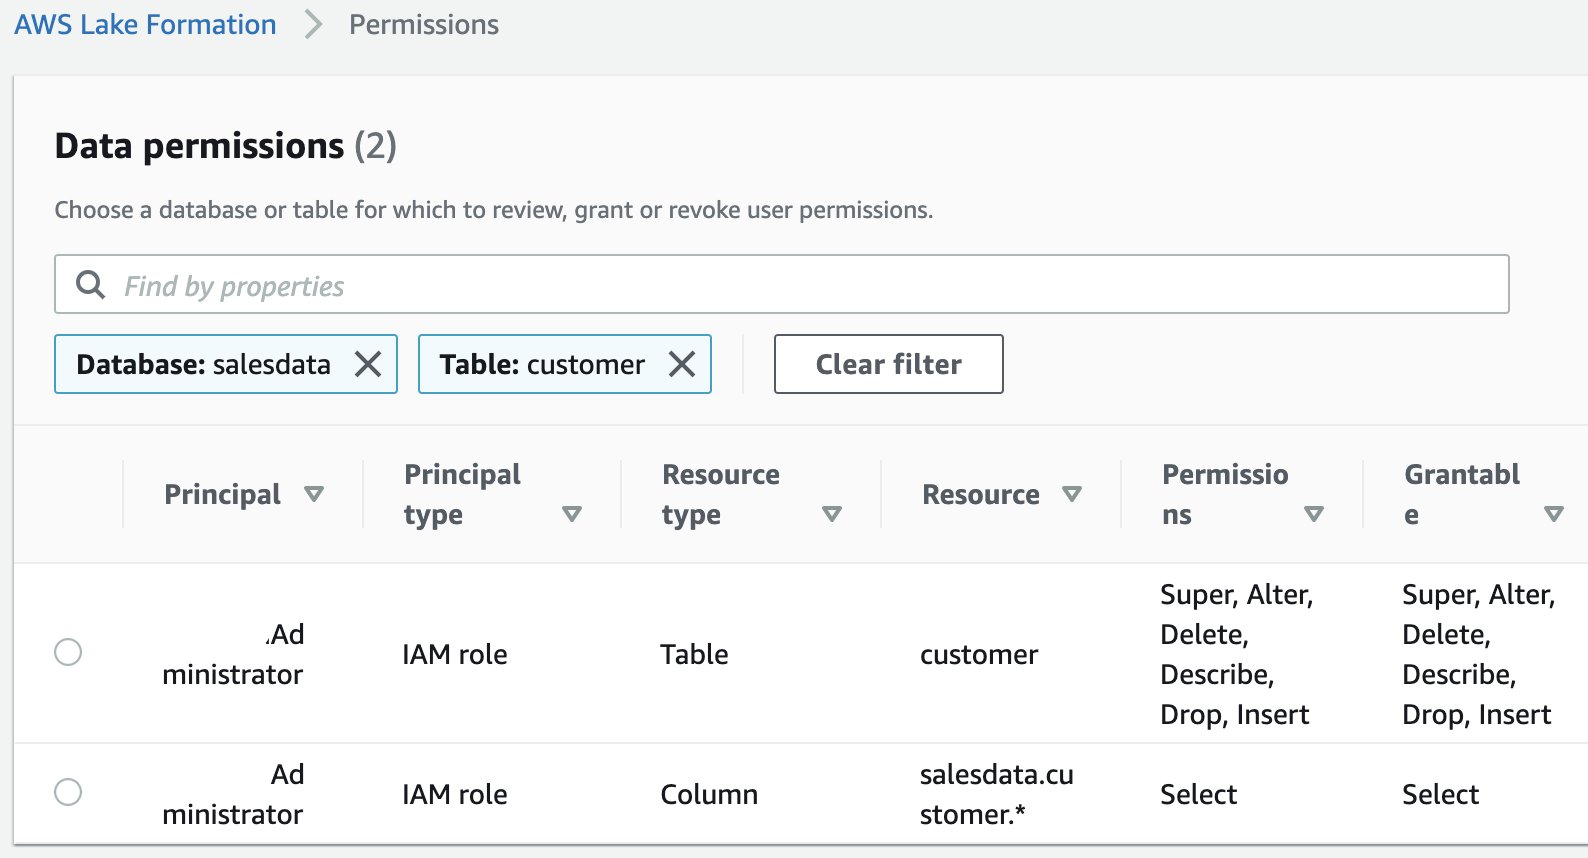
  3. Select the customer table and on the Actions menu, choose View permissions.

You should see following existing permissions. These entries allow the current data lake administrator to access the table and all its columns.
  1. To add new permissions, select the table and on the Actions menu, choose Grant.
  2. Select SAML user and groups.
  3. For SAML and Amazon QuickSight users and groups, enter arn:aws:iam::<AWS ACCOUNT NUMBER>:saml-provider/adfs-saml-provider:group/data-customer.

To get this value, get the ARN of the SAML provider from the IAM console and append :group/data-customer to the end of it.

  1. Select Named data catalog resources.
  2. For Databases, choose the salesdata database.
  3. For Tables, choose the customer table.
  4. For Table permissions, select Select.
  5. For Data permissions, select Column-based access.
  6. For Select columns, add the columns c_city, c_custkey, c_mktsegment, c_nation, and c_region.
  7. Choose Grant.

You have now allowed members of the AD group data-customer to have access to columns of the customer table that don’t include PII.

  1. Repeat these steps for the customer table and data-customer-pii group with all data access.
  2. Repeat these steps for the lineorder table and data-order group with all data access.

Set up a SQL client with JDBC connection and verify permissions

In this post, we use SQL Workbench to access Athena through AD authentication and verify the Lake Formation permissions you created in the previous section.

Prepare the SQL client

To set up the SQL client, complete the following steps:

  1. Download and extract the Lake Formation-compatible Athena JDBC driver with AWS SDK (2.0.14 or later version) from Using Athena with the JDBC Driver.
  2. Go to the SQL Workbench/J website and download the latest stable package.
  3. Install SQL Workbench/J on your client computer.
  4. In SQL Workbench, on the File menu, choose Manage Drivers.
  5. Choose the New driver icon.
  6. For Name, enter Athena JDBC Driver.
  7. For Library, browse to and choose the Simba Athena JDBC .jar file that you just downloaded.
  8. Choose OK.

You’re now ready to create connections in SQL Workbench for your users.

Create connections in SQL Workbench

To create your connections, complete the following steps:

  1. On the File menu, choose Connect.
  2. Enter the name Athena-FinanceUser.
  3. For Driver, choose the Simba Athena JDBC driver.
  4. For URL, enter the following code (replace the placeholders with actual values from your setup and remove the line breaks to make a single line connection string):
jdbc:awsathena://AwsRegion=<AWS Region Name e.g. ap-southeast-2>;
S3OutputLocation=s3://<Athena Query Result Bucket Name>/jdbc;
plugin_name=com.simba.athena.iamsupport.plugin.AdfsCredentialsProvider;
idp_host=<adfs-server-name e.g. adfs.company.com>;
idp_port=443;
preferred_role=<ARN of the role created in step1 e.g. arn>;
user=financeuser@<Domain Name e.g. company.com>;
password=<password>;
SSL_Insecure=true;
LakeFormationEnabled=true;

For this post, we used a self-signed certificate with AD FS. This certificate is not trusted by the client, therefore authentication doesn’t succeed. This is why the SSL_Insecure attribute is set to true to allow authentication despite the self-signed certificate. In real-world setups, you would use valid trusted certificates and can remove the SSL_Insecure attribute.

  1. Create a new SQL workbench profile named Athena-CustomerOpsUser and repeat the earlier steps with CustomerOpsUser in the connection URL string.
  2. To test the connections, choose Test for each user, and confirm that the connection succeeds.

Verify access permissions

Now we can verify permissions for FinanceUser. In the SQL Workbench Statement window, run the following SQL SELECT statement:

SELECT * FROM "salesdata"."lineorder" limit 10;
SELECT * FROM "salesdata"."customer" limit 10;

Verify that only non-PII columns are returned from the customer table.
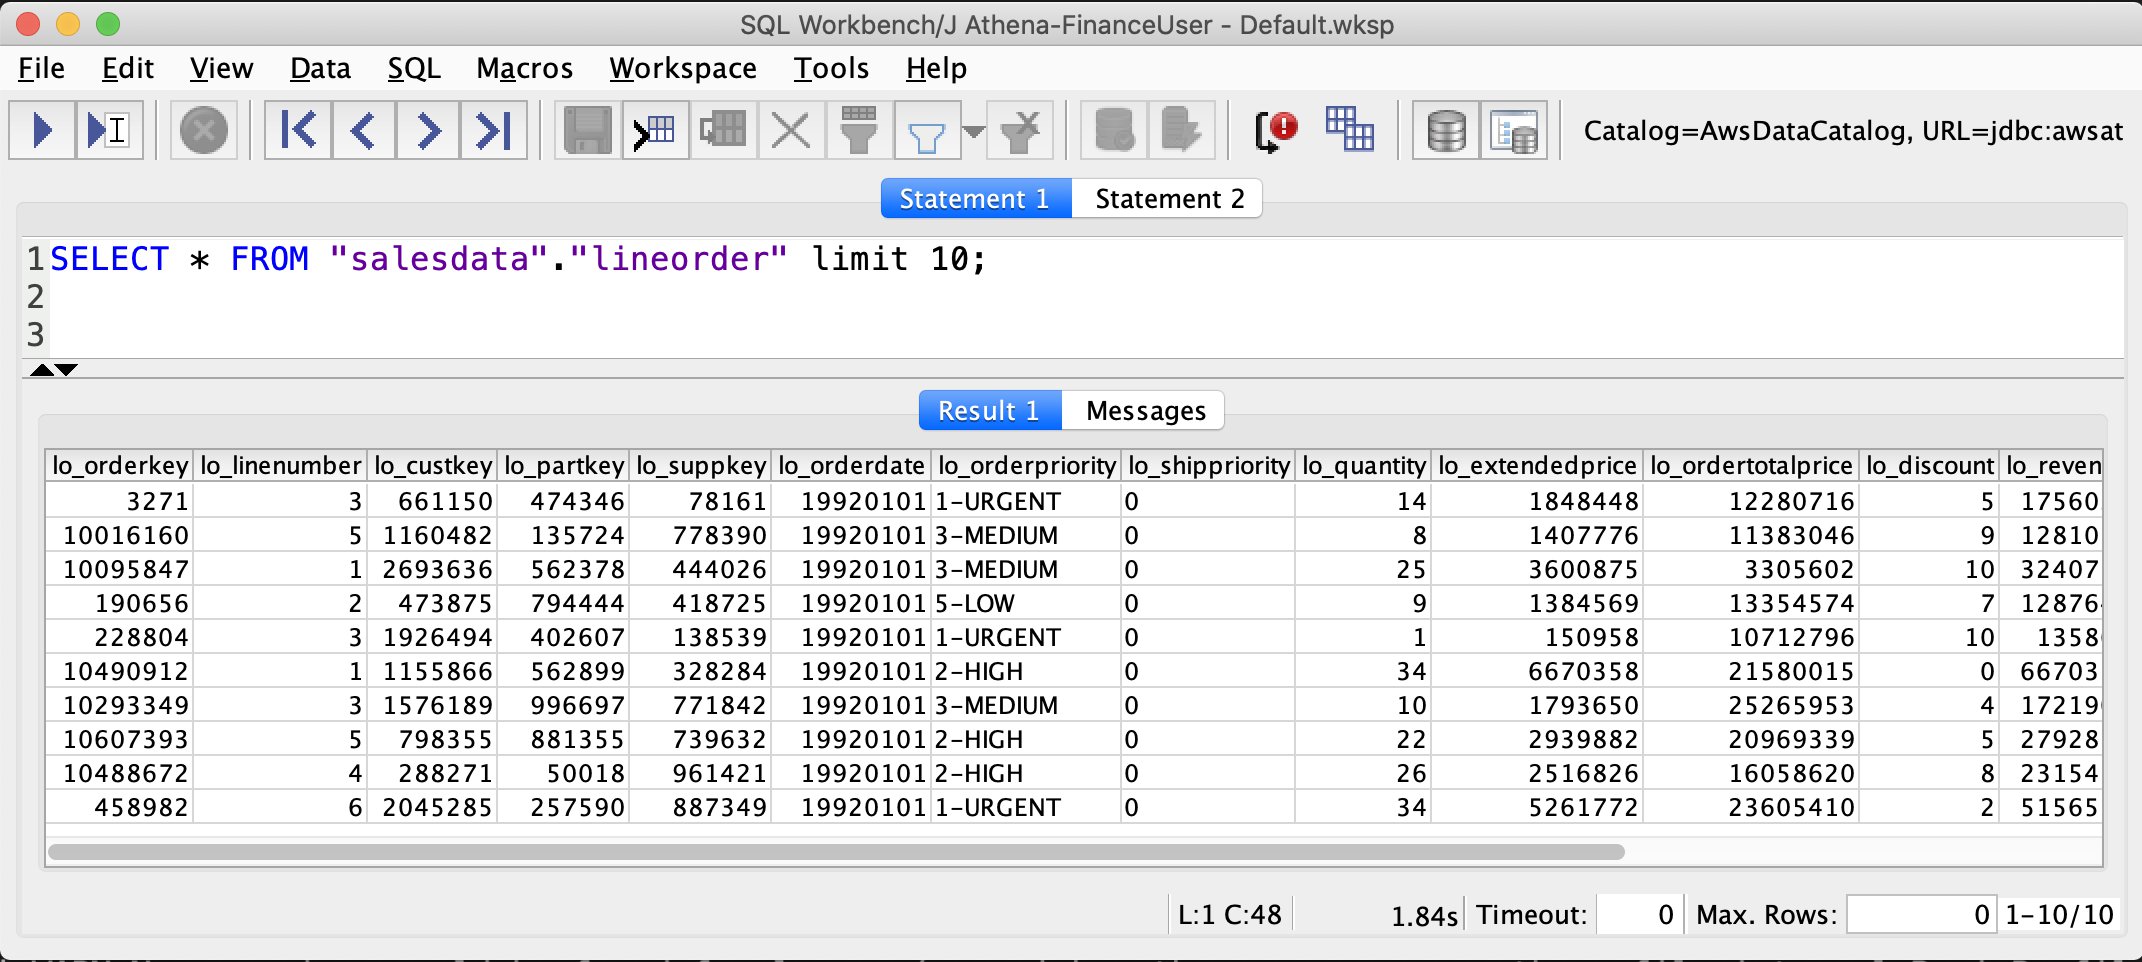
As you see in the preceding screenshots, FinanceUser only has access to non-PII columns of the customer table and full access to (all columns) of the lineorder table. This allows FinanceUser, for example, to run aggregate and summary queries based on market segment or location of customers without having access to their personal information.

Run a similar query for CustomerOpsUser. You should be able to see all columns, including columns containing PII, in the customer table.

Conclusion

This post demonstrated how to configure your data lake permissions using Lake Formation for AD users and groups. We configured AD FS 3.0 on your Active Directory and used it as an IdP to federate into AWS using SAML. This post also showed how you can integrate your Athena JDBC driver to AD FS and use your AD credentials directly to connect to Athena.

Integrating your Active Directory with the Athena JDBC driver gives you the flexibility to access Athena from business intelligence tools you’re already familiar with to analyze the data in your Amazon S3 data lake. This enables you to have a consistent central permission model that is managed through AD users and their group memberships.


About the Authors
Mostafa Safipour is a Solutions Architect at AWS based out of Sydney. Over the past decade he has helped many large organizations in the ANZ region build their data, digital, and enterprise workloads on AWS.

Praveen Kumar is a Specialist Solution Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-native services. His areas of interests are serverless technology, streaming applications, and modern cloud data warehouses.
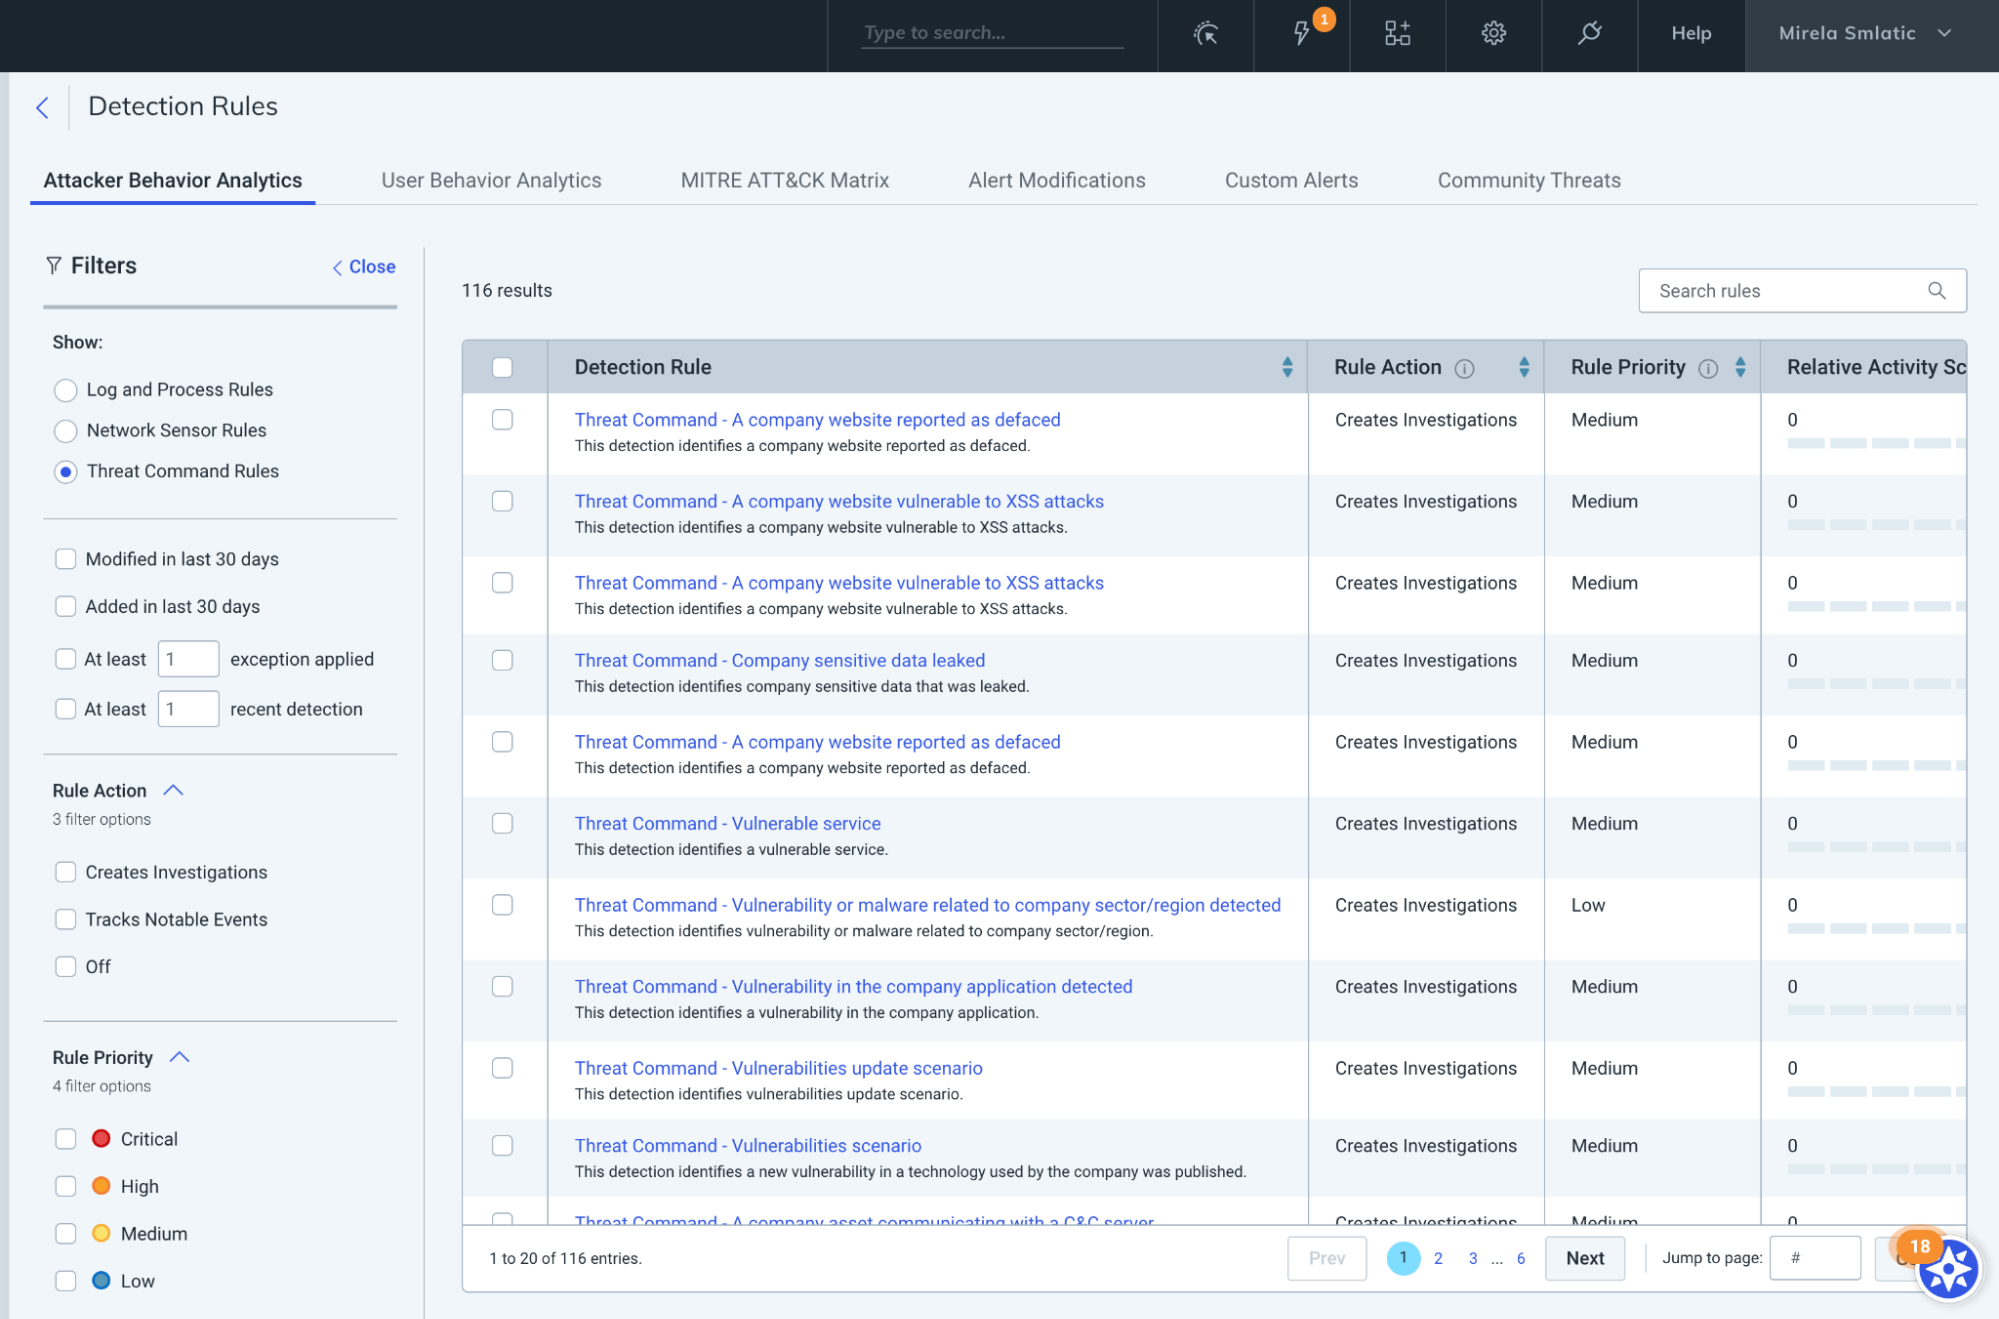
360-Degree XDR and Attack Surface Coverage With Rapid7

Post Syndicated from Margaret Wei original https://blog.rapid7.com/2022/08/18/360-degree-xdr-and-attack-surface-coverage-with-rapid7/

360-Degree XDR and Attack Surface Coverage With Rapid7

Today’s already resource-constrained security teams are tasked with protecting more as environments sprawl and alerts pile up, while attackers continue to get stealthier and add to their arsenal. To be successful against bad actors, security teams need to be proactive against evolving attacks in their earliest stages and ready to detect and respond to advanced threats that make it past defenses (because they will).

Eliminate blindspots and extinguish threats earlier and faster

Rapid7’s external threat intelligence solution, Threat Command, reduces the noise of numerous threat feeds and external sources, and prioritizes and alerts on the most relevant threats to your organization. When used alongside InsightIDR, Rapid7’s next-gen SIEM and XDR, and InsightConnect, Rapid7’s SOAR solution, you’ll unlock a complete view of your internal and external attack surface with unmatched signal to noise.

Leverage InsightIDR, Threat Command, and InsightConnect to:

  • Gain 360-degree visibility with expanded coverage beyond the traditional network perimeter thanks to Threat Command alerts being ingested into InsightIDR, giving you a more holistic picture of your threat landscape.
  • Proactively thwart attack plans with Threat Command alerts that identify active threats from across your attack surface.
  • Find and eliminate threats faster when you correlate and investigate Threat Command alerts with InsightIDR’s rich investigative capabilities.
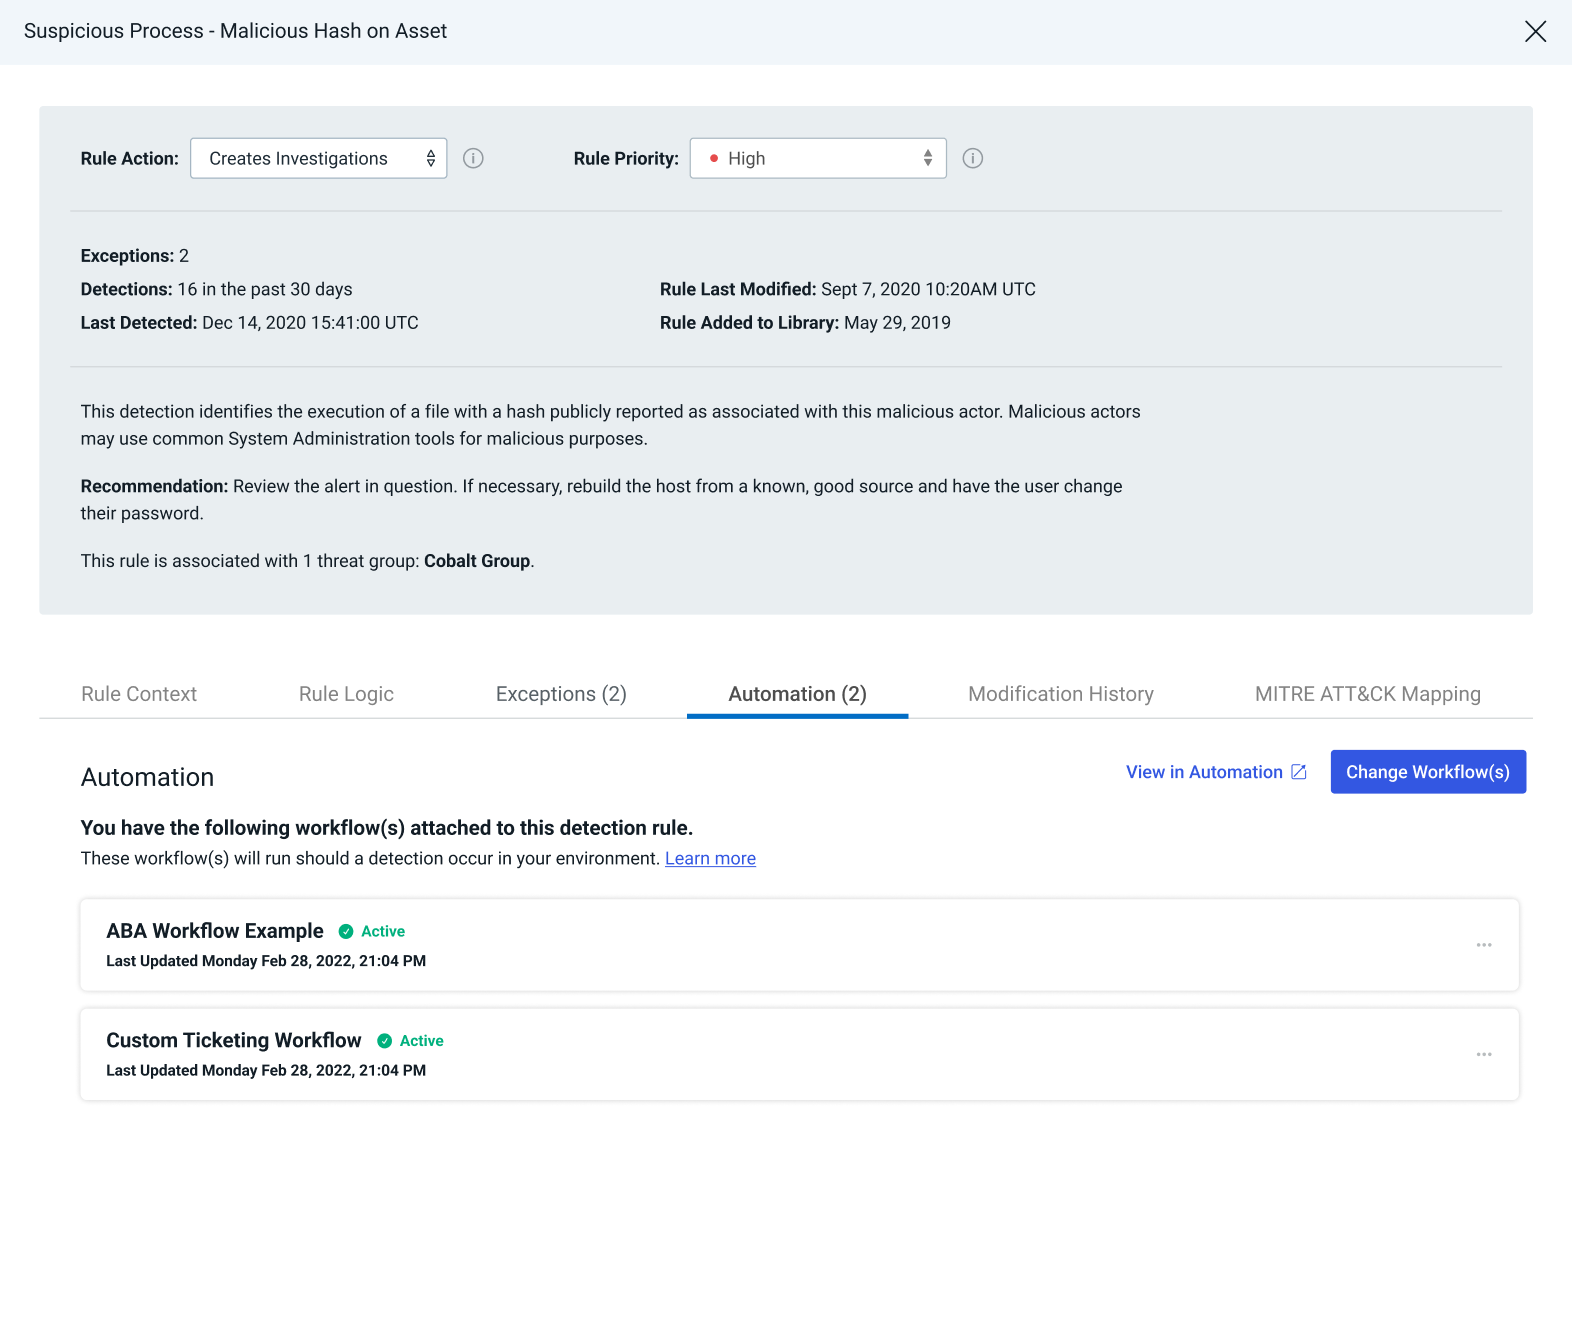
  • Automate your response by attaching an InsightConnect workflow to take action as soon as a detection or a Threat Command alert surfaces in InsightIDR.
360-Degree XDR and Attack Surface Coverage With Rapid7
Threat Command alerts alongside InsightIDR Detection Rules

Stronger signal to noise with Threat Command Threat Library

The power of InsightIDR and Threat Command doesn’t end there. We added another layer to our threat intelligence earlier this year when we integrated Threat Command’s Threat Library into InsightIDR to give more visibility into new indicators of compromise (IOCs) and continued strength around signal to noise.

All IOCs related to threat actors tracked in Threat Command are automatically applied to customer data sent to InsightIDR, which means you automatically get current and future coverage as new IOCs are found by the research team. Alongside InsightIDR’s variety of detection types — User Behavior Analytics (UBA), Attacker Behavior Analytics (ABA), and custom detections — you’re covered against all infiltrations, from lateral movement to unique attacker behaviors and everything in between. The impact? Your team is never behind on emerging threats to your organization.

Faster, more efficient responses with InsightConnect

Strong signal to noise is taken a step further with automation, so teams can not only identify threats quickly but respond immediately. The expanded integration between InsightConnect and InsightIDR allows you to respond to any alert being generated in your environment. With this, you can easily create and map InsightConnect workflows to any ABA, UBA, or custom detection rule, so tailored response actions can be initiated as soon as there is a new detection.

See something suspicious that didn’t trip a detection? You can invoke on-demand automation with integrated Quick Actions from any page in InsightIDR.

360-Degree XDR and Attack Surface Coverage With Rapid7
Mapping of InsightConnect workflows to an ABA alert in InsightIDR

Sophisticated XDR without any headaches

With Rapid7, you’ll achieve sophisticated detection and response outcomes with greater efficiency and efficacy — no matter where you and your team are on your security journey. Stay up to date on the latest from InsightIDR, Threat Command, and InsightConnect as we continue to up-level our cross-product integrations to bring you the most comprehensive XDR solution.

Additional reading:

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

[$] The growing image-processor unpleasantness

Post Syndicated from original https://lwn.net/Articles/904776/

There was a time when care had to be taking when buying hardware if the
goal was to run Linux on it. The situation has improved considerably in
recent decades, and unsupported hardware is more the exception than the
rule. That has, for many years, been especially true of Intel hardware;
that company has made a point of ensuring that its offerings work with
Linux. So it is a bit surprising that the IPU6 image processor shipped
with Alder Lake CPUs
lacks support in Linux, and is unlikely to get it anytime soon. The
problem highlighted here goes beyond just Intel, though.

LibreOffice 7.4 Community released

Post Syndicated from original https://lwn.net/Articles/905088/

The Document Foundation has announced the release of LibreOffice 7.4 Community, which is the community-supported version of the open-source office suite. Version 7.4 comes with new features for the suite as a whole (WebP and EMZ/WMZ support, …), the Writer word-processor (better change tracking and hyphenation settings, …), the Calc spreadsheet (16K columns, …), and more. “Development is now focused on interoperability with Microsoft’s proprietary file formats, and many new features are targeted at users migrating from MS Office“. More information can be found in the release notes.

Krita 5.1.0 released

Post Syndicated from original https://lwn.net/Articles/905075/

Version 5.1.0
of the Krita painting program is out. “Krita 5.1 comes with a ton of
smaller improvements and technical polish. This release sees updates to
usability across the board, improved file format handling, and a whole lot
of changes to the selection and fill tools.
”

Security updates for Thursday

Post Syndicated from original https://lwn.net/Articles/905072/

Security updates have been issued by Debian (chromium, epiphany-browser, freecad, and schroot), Fedora (freeciv, microcode_ctl, qemu, and rsync), Oracle (httpd), SUSE (aws-efs-utils, python-ansi2html, python-py, python-pytest-html, python-pytest-metadata, python-pytest-rerunfailures, python-coverage, python-oniconfig, python-unittest-mixins, bluez, curl, gnutls, kernel, ntfs-3g_ntfsprogs, podman, and ucode-intel), and Ubuntu (zlib).

USB “Rubber Ducky” Attack Tool

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2022/08/usb-rubber-ducky-attack-tool.html

The USB Rubber Ducky is getting better and better.

Already, previous versions of the Rubber Ducky could carry out attacks like creating a fake Windows pop-up box to harvest a user’s login credentials or causing Chrome to send all saved passwords to an attacker’s webserver. But these attacks had to be carefully crafted for specific operating systems and software versions and lacked the flexibility to work across platforms.

The newest Rubber Ducky aims to overcome these limitations. It ships with a major upgrade to the DuckyScript programming language, which is used to create the commands that the Rubber Ducky will enter into a target machine. While previous versions were mostly limited to writing keystroke sequences, DuckyScript 3.0 is a feature-rich language, letting users write functions, store variables, and use logic flow controls (i.e., if this… then that).

That means, for example, the new Ducky can run a test to see if it’s plugged into a Windows or Mac machine and conditionally execute code appropriate to each one or disable itself if it has been connected to the wrong target. It also can generate pseudorandom numbers and use them to add variable delay between keystrokes for a more human effect.

Perhaps most impressively, it can steal data from a target machine by encoding it in binary format and transmitting it through the signals meant to tell a keyboard when the CapsLock or NumLock LEDs should light up. With this method, an attacker could plug it in for a few seconds, tell someone, “Sorry, I guess that USB drive is broken,” and take it back with all their passwords saved.

[Security Nation] Jen and Tod on Hacker Summer Camp 2022

Post Syndicated from Rapid7 original https://blog.rapid7.com/2022/08/18/security-nation-jen-and-tod-on-hacker-summer-camp-2022/

[Security Nation] Jen and Tod on Hacker Summer Camp 2022

In this episode of Security Nation, Tod and Jen chat about their experience at this year’s Hacker Summer Camp, the multi-event lineup of cybersecurity conferences in Las Vegas that includes BSides, Black Hat, and DEF CON. Tod gives us his highlights from the virtual sessions, and Jen recounts her jam-packed week of presentations (which resulted in a somewhat diminished ability to use her voice for this recording).

No Rapid Rundown this week, since our Vegas wrap-up overlaps with much of the latest security news, making it a Rapid Rundown in itself!

Show notes

Learn more about some of our favorite presentations from the Vegas conferences, including:

Like the show? Want to keep Jen and Tod in the podcasting business? Feel free to rate and review with your favorite podcast purveyor, like Apple Podcasts.

Want More Inspiring Stories From the Security Community?

Subscribe to Security Nation Today

[$] Tornado Cash and collateral damage

Post Syndicated from original https://lwn.net/Articles/904960/

On August 8, the US government sanctioned
the Tornado Cash
cryptocurrency
mixer for money laundering. The sanction means that no US citizen or
company can interact with Tornado Cash in any way, all assets of the
organization are to be reported so that they can be seized, and more. But
at the core of Tornado Cash is a chunk of open-source code for “smart contracts”
that run in the Ethereum blockchain; that
code was “seized” as well. There
are some disturbing implications here for our communities.

Using custom consumer group ID support for the AWS Lambda event sources for MSK and self-managed Kafka

Post Syndicated from James Beswick original https://aws.amazon.com/blogs/compute/using-custom-consumer-group-id-support-for-the-aws-lambda-event-sources-for-msk-and-self-managed-kafka/

This post is written by Adam Wagner, Principal Serverless Specialist SA.

AWS Lambda already supports Amazon Managed Streaming for Apache Kafka (MSK) and self-managed Apache Kafka clusters as event sources. Today, AWS adds support for specifying a custom consumer group ID for the Lambda event source mappings (ESMs) for MSK and self-managed Kafka event sources.

With this feature, you can create a Lambda ESM that uses a consumer group that has already been created. This enables you to use Lambda as a Kafka consumer for topics that are replicated with MirrorMaker v2 or with consumer groups you create to start consuming at a particular offset or timestamp.

Overview

This blog post shows how to use this feature to enable Lambda to consume a Kafka topic starting at a specific timestamp. This can be useful if you must reprocess some data but don’t want to reprocess all of the data in the topic.

In this example application, a client application writes to a topic on the MSK cluster. It creates a consumer group that points to a specific timestamp within that topic as the starting point for consuming messages. A Lambda ESM is created using that existing consumer group that triggers a Lambda function. This processes and writes the messages to an Amazon DynamoDB table.

Reference architecture

  1. A Kafka client writes messages to a topic in the MSK cluster.
  2. A Kafka consumer group is created with a starting point of a specific timestamp
  3. The Lambda ESM polls the MSK topic using the existing consumer group and triggers the Lambda function with batches of messages.
  4. The Lambda function writes the messages to DynamoDB

Step-by-step instructions

To get started, create an MSK cluster and a client Amazon EC2 instance from which to create topics and publish messages. If you don’t already have an MSK cluster, follow this blog on setting up an MSK cluster and using it as an event source for Lambda.

  1. On the client instance, set an environment variable to the MSK cluster bootstrap servers to make it easier to reference them in future commands:
    export MSKBOOTSTRAP='b-1.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094,b-2.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094,b-3.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094'
  2. Create the topic. This example has a three-node MSK cluster so the replication factor is also set to three. The partition count is set to three in this example. In your applications, set this according to throughput and parallelization needs.
    ./bin/kafka-topics.sh --create --bootstrap-server $MSKBOOT --replication-factor 3 --partitions 3 --topic demoTopic01
  3. Write messages to the topic using this Python script:
    #!/usr/bin/env python3
    import json
    import time
    from random import randint
    from uuid import uuid4
    from kafka import KafkaProducer
    
    BROKERS = ['b-1.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094', 
            'b-2.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094',
            'b-3.mskcluster.oy1hqd.c23.kafka.us-east-1.amazonaws.com:9094']
    TOPIC = 'demoTopic01'
    
    producer = KafkaProducer(bootstrap_servers=BROKERS, security_protocol='SSL',
            value_serializer=lambda x: json.dumps(x).encode('utf-8'))
    
    def create_record(sequence_num):
        number = randint(1000000,10000000)
        record = {"id": sequence_num, "record_timestamp": int(time.time()), "random_number": number, "producer_id": str(uuid4()) }
        print(record)
        return record
    
    def publish_rec(seq):
        data = create_record(seq)
        producer.send(TOPIC, value=data).add_callback(on_send_success).add_errback(on_send_error)
        producer.flush()
    
    def on_send_success(record_metadata):
        print(record_metadata.topic, record_metadata.partition, record_metadata.offset)
    
    def on_send_error(excp):
        print('error writing to kafka', exc_info=excp)
    
    for num in range(1,10000000):
        publish_rec(num)
        time.sleep(0.5) 
    
  4. Copy the script into a file on the client instance named producer.py. The script uses the kafka-python library, so first create a virtual environment and install the library.
    python3 -m venv venv
    source venv/bin/activate
    pip3 install kafka-python
    
  5. Start the script. Leave it running for a few minutes to accumulate some messages in the topic.
    Output
  6. Previously, a Lambda function would choose between consuming messages starting at the beginning of the topic or starting with the latest messages. In this example, it starts consuming messages from a few hours ago at 14:30 UTC. To do this, first create a new consumer group on the client instance:
    ./bin/kafka-consumer-groups.sh --command-config client.properties --bootstrap-server $MSKBOOTSTRAP --topic demoTopic01 --group specificTimeCG --to-datetime 2022-08-10T16:00:00.000 --reset-offsets --execute
  7. In this case, specificTimeCG is the consumer group ID used when creating the Lambda ESM. Listing the consumer groups on the cluster shows the new group:
    ./bin/kafka-consumer-groups.sh --list --command-config client.properties --bootstrap-server $MSKBOOTSTRAP

    Output

  8. With the consumer group created, create the Lambda function along with the Event Source Mapping that uses this new consumer group. In this case, the Lambda function and DynamoDB table are already created. Create the ESM with the following AWS CLI Command:
    aws lambda create-event-source-mapping --region us-east-1 --event-source-arn arn:aws:kafka:us-east-1:0123456789:cluster/demo-us-east-1/78a8d1c1-fa31-4f59-9de3-aacdd77b79bb-23 --function-name msk-consumer-demo-ProcessMSKfunction-IrUhEoDY6X9N --batch-size 3 --amazon-managed-kafka-event-source-config '{"ConsumerGroupId":"specificTimeCG"}' --topics demoTopic01

    The event source in the Lambda console or CLI shows the starting position set to TRIM_HORIZON. However, if you specify a custom consumer group ID that already has existing offsets, those offsets take precedent.

  9. With the event source created, navigate to the DynamoDB console. Locate the DynamoDB table to see the records written by the Lambda function.
    DynamoDB table

Converting the record timestamp of the earliest record in DynamoDB, 1660147212, to a human-readable date shows that the first record was created on 2022-08-10T16:00:12.

In this example, the consumer group is created before the Lambda ESM so that you can specify the timestamp to start from.

If you create an ESM and specify a custom consumer group ID that does not exist, it is created. This is a convenient way to create a new consumer group for an ESM with an ID of your choosing.

Deleting an ESM does not delete the consumer group, regardless of whether it is created before, or during, the ESM creation.

Using the AWS Serverless Application Model (AWS SAM)

To create the event source mapping with a custom consumer group using an AWS Serverless Application Model (AWS SAM) template, use the following snippet:

Events:
  MyMskEvent:
    Type: MSK
    Properties:
      Stream: !Sub arn:aws:kafka:${AWS::Region}:012345678901:cluster/ demo-us-east-1/78a8d1c1-fa31-4f59-9de3-aacdd77b79bb-23
      Topics:
        - "demoTopic01"
      ConsumerGroupId: specificTimeCG

Other types of Kafka clusters

This example uses the custom consumer group ID feature when consuming a Kafka topic from an MSK cluster. In addition to MSK clusters, this feature also supports self-managed Kafka clusters. These could be clusters running on EC2 instances or managed Kafka clusters from a partner such as Confluent.

Conclusion

This post shows how to use the new custom consumer group ID feature of the Lambda event source mapping for Amazon MSK and self-managed Kafka. This feature can be used to consume messages with Lambda starting at a specific timestamp or offset within a Kafka topic. It can also be used to consume messages from a consumer group that is replicated from another Kafka cluster using MirrorMaker v2.

For more serverless learning resources, visit Serverless Land.

Amazon Redshift data sharing best practices and considerations

Post Syndicated from BP Yau original https://aws.amazon.com/blogs/big-data/amazon-redshift-data-sharing-best-practices-and-considerations/

Amazon Redshift is a fast, fully managed cloud data warehouse that makes it simple and cost-effective to analyze all your data using standard SQL and your existing business intelligence (BI) tools. Amazon Redshift data sharing allows for a secure and easy way to share live data for reading across Amazon Redshift clusters. It allows an Amazon Redshift producer cluster to share objects with one or more Amazon Redshift consumer clusters for read purposes without having to copy the data. With this approach, workloads isolated to different clusters can share and collaborate frequently on data to drive innovation and offer value-added analytic services to your internal and external stakeholders. You can share data at many levels, including databases, schemas, tables, views, columns, and user-defined SQL functions, to provide fine-grained access controls that can be tailored for different users and businesses that all need access to Amazon Redshift data. The feature itself is simple to use and integrate into existing BI tools.

In this post, we discuss Amazon Redshift data sharing, including some best practices and considerations.

How does Amazon Redshift data sharing work ?

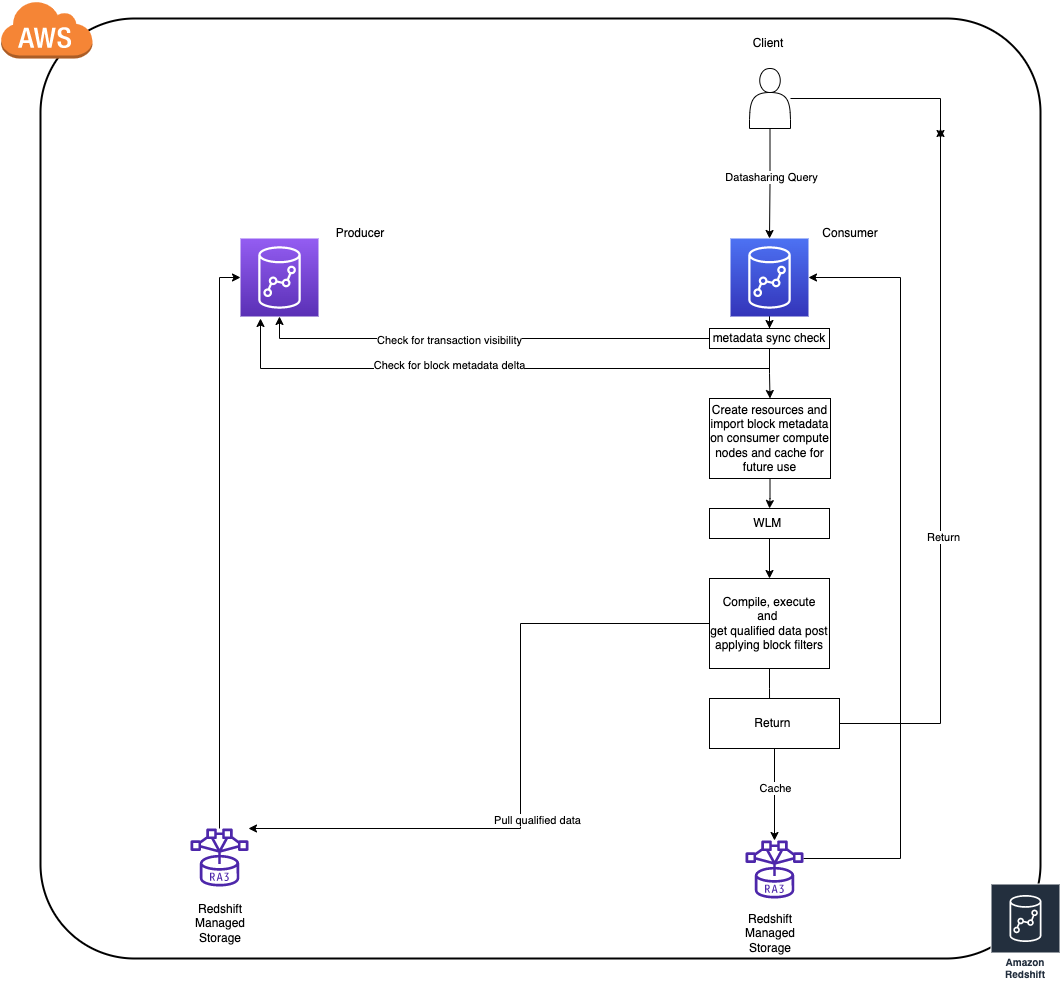
  • To achieve best in class performance Amazon Redshift consumer clusters cache and incrementally update block level data (let us refer to this as block metadata) of objects that are queried, from the producer cluster (this works even when cluster is paused).
  • The time taken for caching block metadata depends on the rate of the data change on the producer since the respective object(s) were last queried on the consumer. (As of today the consumer clusters only update their metadata cache for an object only on demand i.e. when queried)
  • If there are frequent DDL operations, the consumer is forced to re-cache the full block metadata for an object during the next access to maintain consistency as to enable live sharing as structure changes on the producer invalidate all the existing metadata cache on the consumers.
  • Once the consumer has the block metadata in sync with the latest state of an object on the producer that is when the query would execute as any other regular query (query referring to local objects).

Now that we have the necessary background on data sharing and how it works, let’s look at a few best practices across streams that can help improve workloads while using data sharing.

Security

In this section, we share some best practices for security when using Amazon Redshift data sharing.

Use INCLUDE NEW cautiously

INCLUDE NEW is a very useful setting while adding a schema to a data share (ALTER DATASHARE). If set to TRUE, this automatically adds all the objects created in the future in the specified schema to the data share automatically. This might not be ideal in cases where you want to have fine-grained control on objects being shared. In these cases, leave the setting at its default of FALSE.

Use views to achieve fine-grained access control

To achieve fine-grained access control for data sharing, you can create late-binding views or materialized views on shared objects on the consumer, and then share the access to these views to users on consumer cluster, instead of giving full access on the original shared objects. This comes with its own set of considerations, which we explain later in this post.

Audit data share usage and changes

Amazon Redshift provides an efficient way to audit all the activity and changes with respect to a data share using system views. We can use the following views to check these details:

Performance

In this section, we discuss best practices related to performance.

Materialized views in data sharing environments

Materialized views (MVs) provide a powerful route to precompute complex aggregations for use cases where high throughput is needed, and you can directly share a materialized view object via data sharing as well.

For materialized views built on tables where there are frequent write operations, it’s ideal to create the materialized view object on the producer itself and share the view. This method gives us the opportunity to centralize the management of the view on the producer cluster itself.

For slowly changing data tables, you can share the table objects directly and build the materialized view on the shared objects directly on the consumer. This method gives us the flexibility of creating a customized view of data on each consumer according to your use case.

This can help optimize the block metadata download and caching times in the data sharing query lifecycle. This also helps in materialized view refreshes because, as of this writing, Redshift doesn’t support incremental refresh for MVs built on shared objects.

Factors to consider when using cross-Region data sharing

Data sharing is supported even if the producer and consumer are in different Regions. There are a few differences we need to consider while implementing a share across Regions:

  • Consumer data reads are charged at $5/TB for cross region data shares, Data sharing within the same Region is free. For more information, refer to Managing cost control for cross-Region data sharing.
  • Performance will also vary when compared to a uni-Regional data share because the block metadata exchange and data transfer process between the cross-Regional shared clusters will take more time due to network throughput.

Metadata access

There are many system views that help with fetching the list of shared objects a user has access to. Some of these include all the objects from the database that you’re currently connected to, including objects from all the other databases that you have access to on the cluster, including external objects. The views are as follows:

We suggest using very restrictive filtering while querying these views because a simple select * will result in an entire catalog read, which isn’t ideal. For example, take the following query:

select * from svv_all_tables;

This query will try to collect metadata for all the shared and local objects, making it very heavy in terms of metadata scans, especially for shared objects.

The following is a better query for achieving a similar result:

SELECT table_name,
column_name,
data_type FROM svv_all_tables WHERE table_name = < tablename > AND schema_name = < schemaname > AND database_name = < databasename > ORDER BY ordinal_position

This is a good practice to follow for all metadata views and tables; doing so allows seamless integration into several tools. You can also use the SVV_DATASHARE* system views to exclusively see shared object-related information.

Producer/consumer dependencies

In this section, we discuss the dependencies between the producer and consumer.

Impact of the consumer on the producer

Queries on the consumer cluster will have no impact in terms of performance or activity on the producer cluster. This is why we can achieve true workload isolation using data sharing.

Encrypted producers and consumers

Data sharing seamlessly integrates even if both the producer and the consumer are encrypted using different AWS Key Management Service (AWS KMS) keys. There are sophisticated, highly secure key exchange protocols to facilitate this so you don’t have to worry about encryption at rest and other compliance dependencies. The only thing to make sure is that both the producer and consumer are in a homogeneous encryption configuration.

Data visibility and consistency

A data sharing query on the consumer can’t impact the transaction semantics on the producer. All the queries involving shared objects on the consumer cluster follow read-committed transaction consistency while checking for visible data for that transaction.

Maintenance

If there is a scheduled manual VACUUM operation in use for maintenance activities on the producer cluster on shared objects, you should use VACUUM recluster whenever possible. This is especially important for large objects because it has optimizations in terms of the number of data blocks the utility interacts with, which results in less block metadata churn compared to a full vacuum. This benefits the data sharing workloads by reducing the block metadata sync times.

Add-ons

In this section, we discuss additional add-on features for data sharing in Amazon Redshift.

Real-time data analytics using Amazon Redshift streaming data

Amazon Redshift recently announced the preview for streaming ingestion using Amazon Kinesis Data Streams. This eliminates the need for staging the data and helps achieve low-latency data access. The data generated via streaming on the Amazon Redshift cluster is exposed using a materialized view. You can share this as any other materialized view via a data share and use it to set up low-latency shared data access across clusters in minutes.

Amazon Redshift concurrency scaling to improve throughput

Amazon Redshift data sharing queries can utilize concurrency scaling to improve the overall throughput of the cluster. You can enable concurrency scaling on the consumer cluster for queues where you expect a heavy workload to improve the overall throughput when the cluster is experiencing heavy load.

For more information about concurrency scaling, refer to Data sharing considerations in Amazon Redshift.

Amazon Redshift Serverless

Amazon Redshift Serverless clusters are ready for data sharing out of the box. A serverless cluster can also act as a producer or a consumer for a provisioned cluster. The following are the supported permutations with Redshift Serverless:

  • Serverless (producer) and provisioned (consumer)
  • Serverless (producer) and serverless (consumer)
  • Serverless (consumer) and provisioned (producer)

Conclusion

Amazon Redshift data sharing gives you the ability to fan out and scale complex workloads without worrying about workload isolation. However, like any system, not having the right optimization techniques in place could pose complex challenges in the long term as the systems grow in scale. Incorporating the best practices listed in this post presents a way to mitigate potential performance bottlenecks proactively in various areas.

Try data sharing today to unlock the full potential of Amazon Redshift, and please don’t hesitate to reach out to us in case of further questions or clarifications.


About the authors

BP Yau is a Sr Product Manager at AWS. He is passionate about helping customers architect big data solutions to process data at scale. Before AWS, he helped Amazon.com Supply Chain Optimization Technologies migrate its Oracle data warehouse to Amazon Redshift and build its next generation big data analytics platform using AWS technologies.

Sai Teja Boddapati is a Database Engineer based out of Seattle. He works on solving complex database problems to contribute to building the most user friendly data warehouse available. In his spare time, he loves travelling, playing games and watching movies & documentaries.

AWS CyberVadis report now available for due diligence on third-party suppliers

Post Syndicated from Andreas Terwellen original https://aws.amazon.com/blogs/security/aws-cybervadis-report-now-available-for-due-diligence-on-third-party-suppliers/

At Amazon Web Services (AWS), we’re continuously expanding our compliance programs to provide you with more tools and resources to perform effective due diligence on AWS. We’re excited to announce the availability of the AWS CyberVadis report to help you reduce the burden of performing due diligence on your third-party suppliers.

With the increase in adoption of cloud products and services across multiple sectors and industries, AWS is a critical component of customers’ third-party environments. Regulated customers, such as those in the financial services sector, are held to high standards by regulators and auditors when it comes to exercising effective due diligence on third parties.

Many customers use third-party cyber risk management (TPCRM) services such as CyberVadis to better manage risks from their evolving third-party environments and to drive operational efficiencies. To help with such efforts, AWS has completed the CyberVadis assessment of its security posture. CyberVadis security analysts perform the assessment and validate the results annually.

CyberVadis is a comprehensive third-party risk assessment process that combines the speed and scalability of automation with the certainty of analyst validation. The CyberVadis cybersecurity rating methodology assesses the maturity of a company’s information security management system (ISMS) through its policies, implementation measures, and results.

CyberVadis integrates responses from AWS with analytics and risk models to provide an in-depth view of the AWS security posture. The CyberVadis methodology maps to major international compliance standards, including the following:

Customers can download the AWS CyberVadis report at no additional cost. For details on how to access the report, see our AWS CyberVadis report page.

As always, we value your feedback and questions. Reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below. To learn more about our other compliance and security programs, see AWS Compliance Programs.

Want more AWS Security news? Follow us on Twitter.

Andreas Terwellen

Andreas Terwellen

Andreas is a senior manager in security audit assurance at AWS, based in Frankfurt, Germany. His team is responsible for third-party and customer audits, attestations, certifications, and assessments across Europe. Previously, he was a CISO in a DAX-listed telecommunications company in Germany. He also worked for different consulting companies managing large teams and programs across multiple industries and sectors.

Manuel Mazarredo

Manuel Mazarredo

Manuel is a security audit program manager at AWS based in Amsterdam, the Netherlands. Manuel leads security audits, attestations, and certification programs across Europe, and is responsible for the BeNeLux area. For the past 18 years, he has worked in information systems audits, ethical hacking, project management, quality assurance, and vendor management across a variety of industries.

AWS Trusted Advisor – New Priority Capability

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-trusted-advisor-new-priority-capability/

AWS Trusted Advisor is a service that continuously analyzes your AWS accounts and provides recommendations to help you to follow AWS best practices and AWS Well-Architected guidelines. Trusted Advisor implements a series of checks. These checks identify ways to optimize your AWS infrastructure, improve security and performance, reduce costs, and monitor service quotas.

Today, we are making available to all Enterprise Support customers a new capability for AWS Trusted Advisor: Trusted Advisor Priority. It gives you prioritized and context-driven recommendations manually curated by your AWS account team, based on their knowledge of your environment and the machine-generated checks from AWS Services.

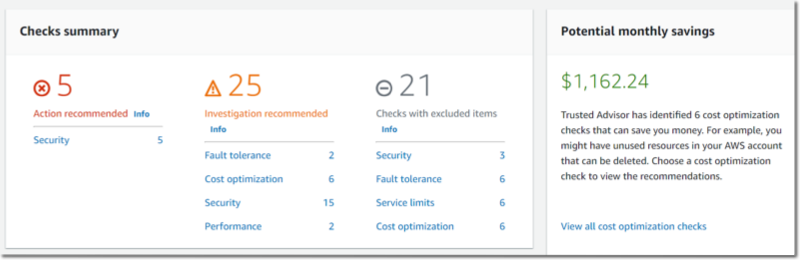
Trusted Advisor implements over 200 checks in five categories: cost optimization, performance, security, fault tolerance, and service limits. Here is a view of the current Trusted Advisor dashboard.

AWS Trusted Advisor Categories

The list of checks available on your account depends on your level of support. When you have AWS Basic Support, available to all customers, or AWS Developer Support, you have access to core security and service limits checks. When you have AWS Business Support or AWS Enterprise Support, you have access to all checks.

The new Priority capability gives you a prioritized view of critical risks. It shows prioritized, contextual recommendations and actionable insights based on your business outcomes and what’s important to you. It also surfaces risks proactively identified by your AWS account team to alert and address critical cloud risks stemming from deviations from AWS best practices. It is designed to help you: IT leaders, technical decisions makers, and members of a Cloud Center of Excellence.

The account team takes advantage of their understanding of your production accounts and business-critical workloads. By working with you, they identify what’s important to you, and the outcomes or goals you wish to achieve. For example, they know about your business viewpoint whether it is exiting a data center by the end of the year, launching a new product, expanding to a new geography, or migrating a workload to the cloud.

Trusted Advisor uses multiple sources to define the priorities. On one side, it uses signals from other AWS services, such as AWS Compute Optimizer, Amazon GuardDuty, or VPC Flow Logs. On the other side, it uses context manually curated by your AWS account team (Account Manager, Technical Account Manager, Solutions Architect, Customer Solutions Manager, and others) and the knowledge they have about your production accounts, business-critical applications and critical workloads. You will be guided to opportunities to take advantage of AWS Support engagements like a Cost Optimization workshop when the account team believes there are opportunities to reduce costs, a deep dive with a service team, or an Infrastructure Event Management for an upcoming workload migration.

You will be alerted to risks in your deployments on AWS, using sources such as the AWS Well-Architected framework. We will highlight and bring to attention any open high risk issues (HRIs) from recently conducted Well-Architected reviews. We also run campaigns to proactively identify, alert, and reduce single points of failures, such as single Availability Zone deployments. This verifies that you don’t have a single point of failures for production applications that are used for mission-critical processes, that drive significant revenue, or have regulated availability requirements. Trusted Advisor helps you to detect, raise awareness, and provide prescriptive guidance.

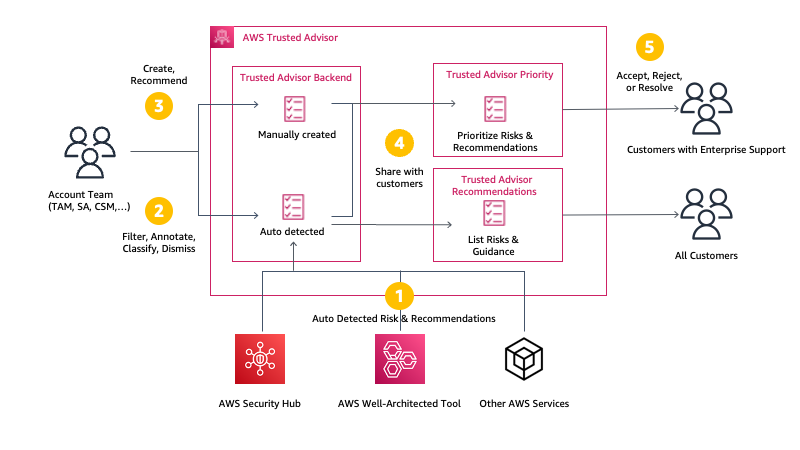
Here is a diagram to visualize my mental model for Trusted Advisor Priority:

Trusted Advisor Mental Model Diagram

Trusted Advisor Priority works with AWS Organizations: it aggregates all recommendations from member accounts in your management account or designed delegated administrator. You may delegate access to Trusted Advisor Priority to a maximum of five other AWS accounts. Trusted Advisor Priority comes with a new AWS Identity and Access Management (IAM) policy to help you manage access to the capability. Finally, you can also configure to receive daily and weekly email digests of all prioritized notifications to the alternate contacts you set up in the management account or each delegated admin account.

Let’s See Trusted Advisor Priority in Action
I open the AWS Management Console and navigate to Trusted Advisor. I notice a new navigation entry on the left menu. It is the default view for Enterprise Support customers.

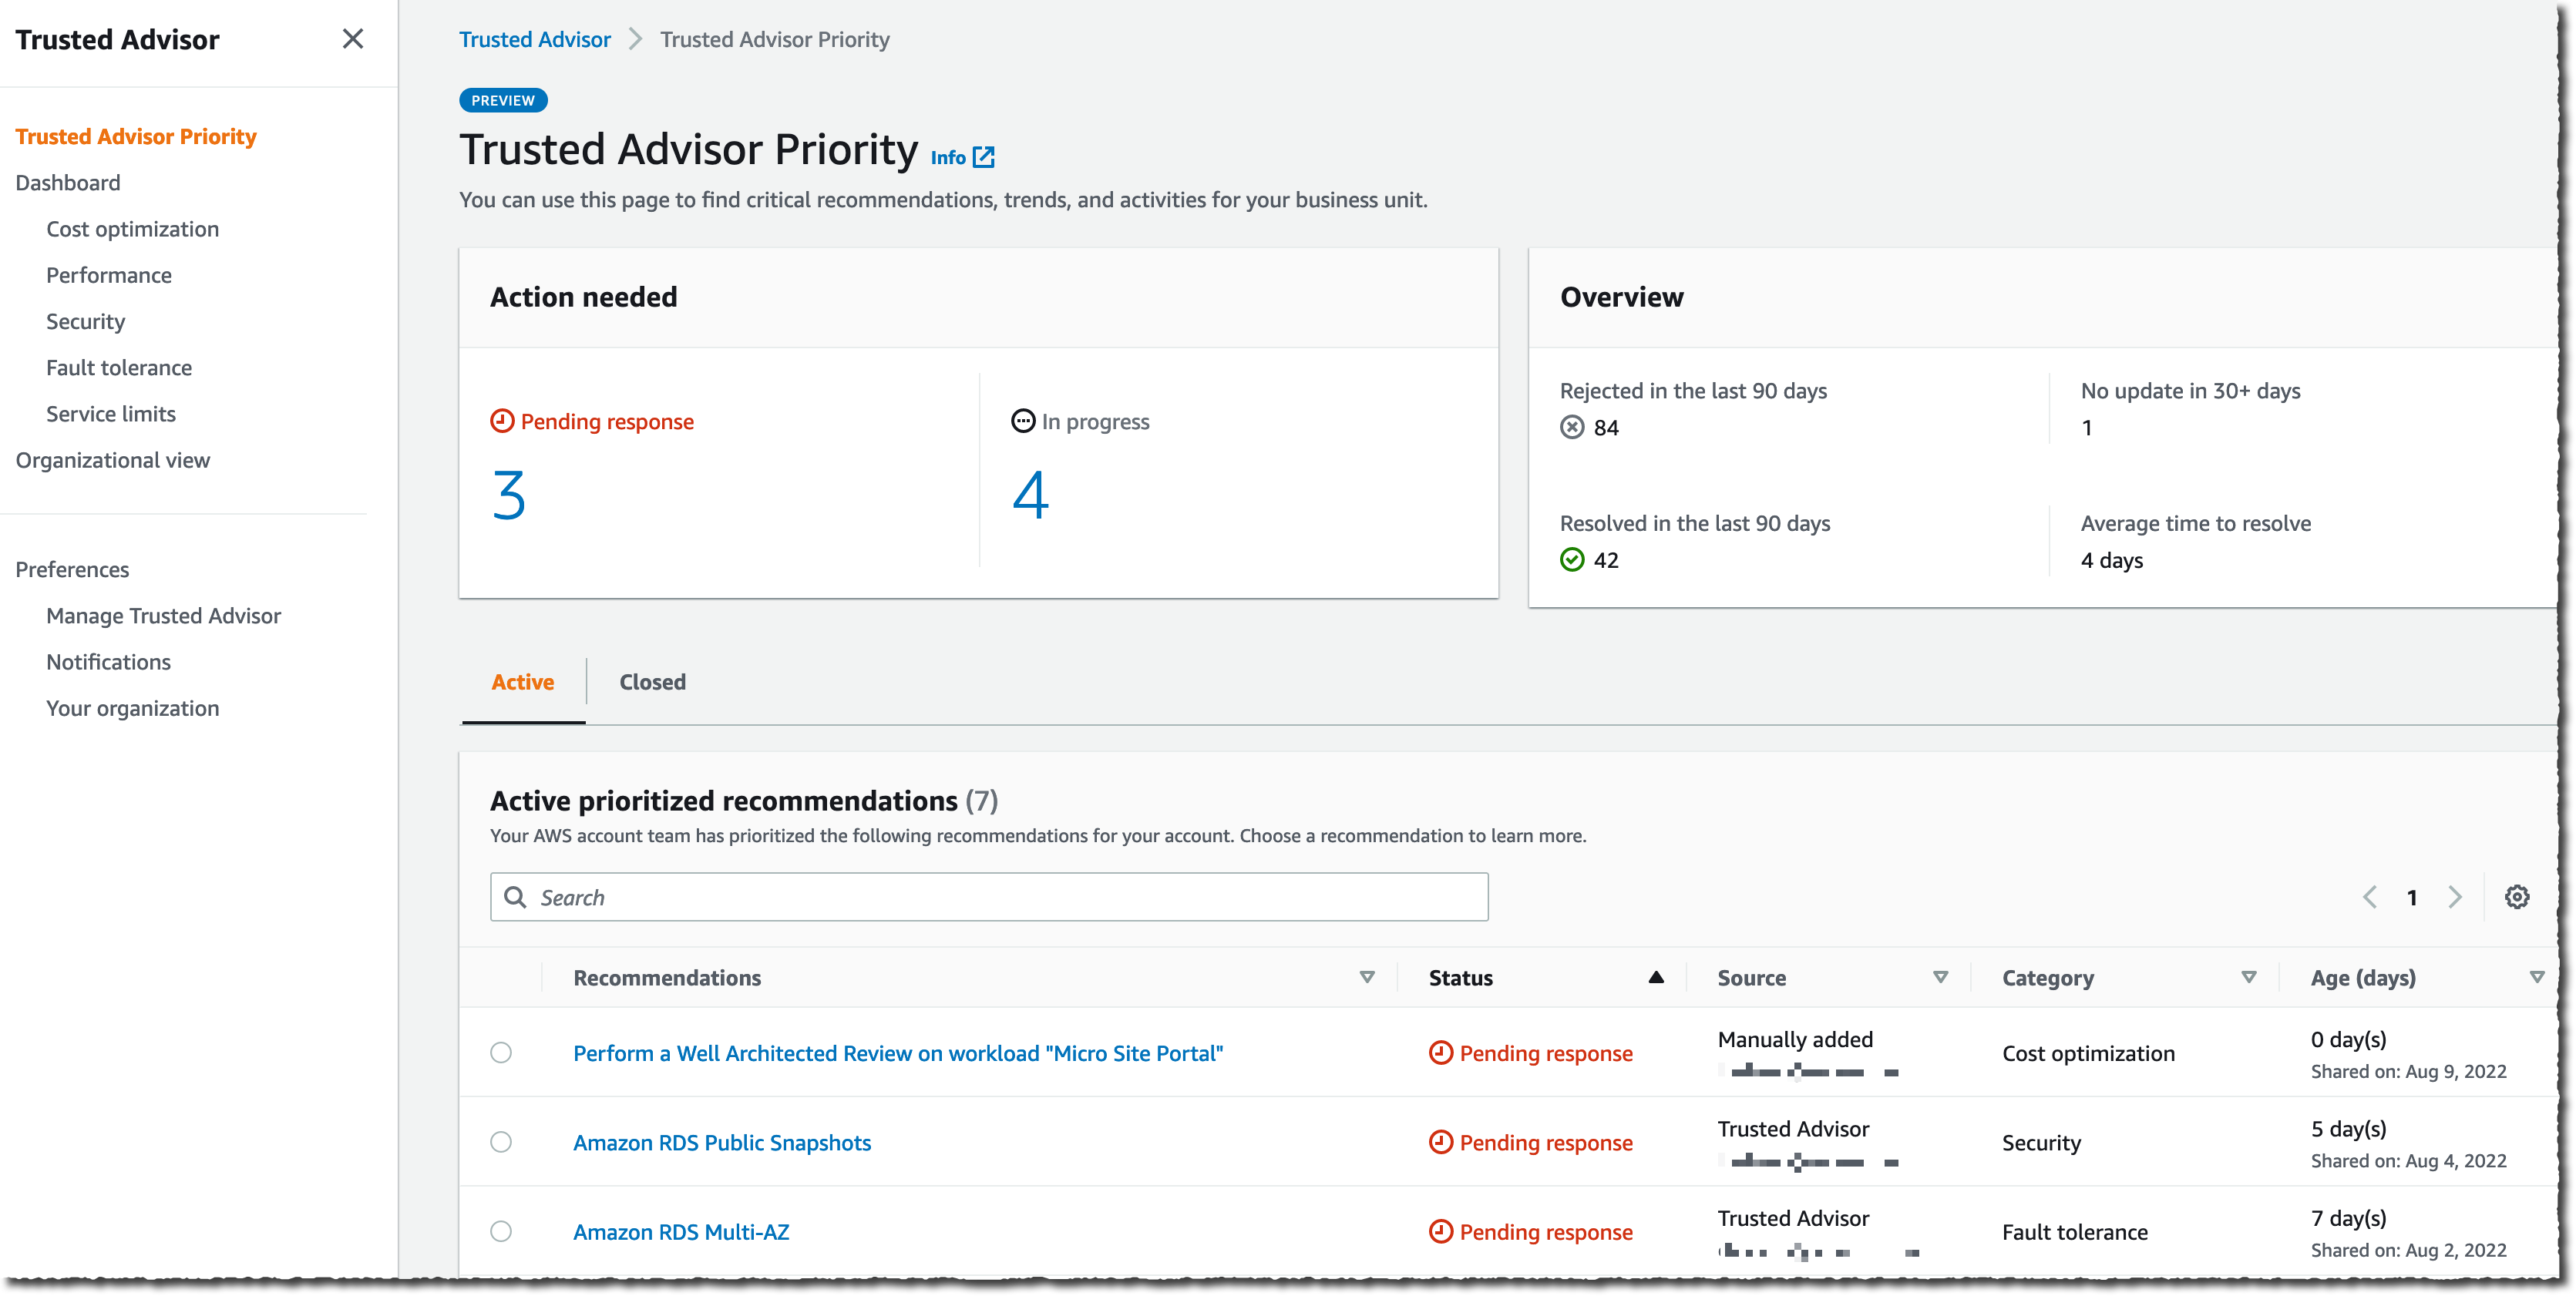
The Trusted Advisor Priority main screen summarizes the number of Pending response and In progress recommendations. It shares some time-related statistics on the right side of the screen. I can start to look at the Active prioritized recommendations list on the bottom half of the screen.

Recommendations are divided into two panels: Active and Closed. The Active tab includes recommendations that have been surfaced to you and which you are actively working on. The Closed tab includes recommendations that have been resolved. All account team prioritized recommendations are presented with a series of searchable and sortable columns. I see the recommendation name, status, source, category, and age.

AWS Trusted Advisor Priority

The list gives me details about the category, the age, and the status of the recommendations. The Source column distinguishes between auto-detected and manually identified opportunities. The Category column shows the category from Trusted Advisor (cost optimization, performance, security, fault tolerance, and service limits). The Age column shows me how long it’s been since the recommendation was first shared. This helps with tracking the time to resolution for each of these items.

AWS Trusted Advisor Priority

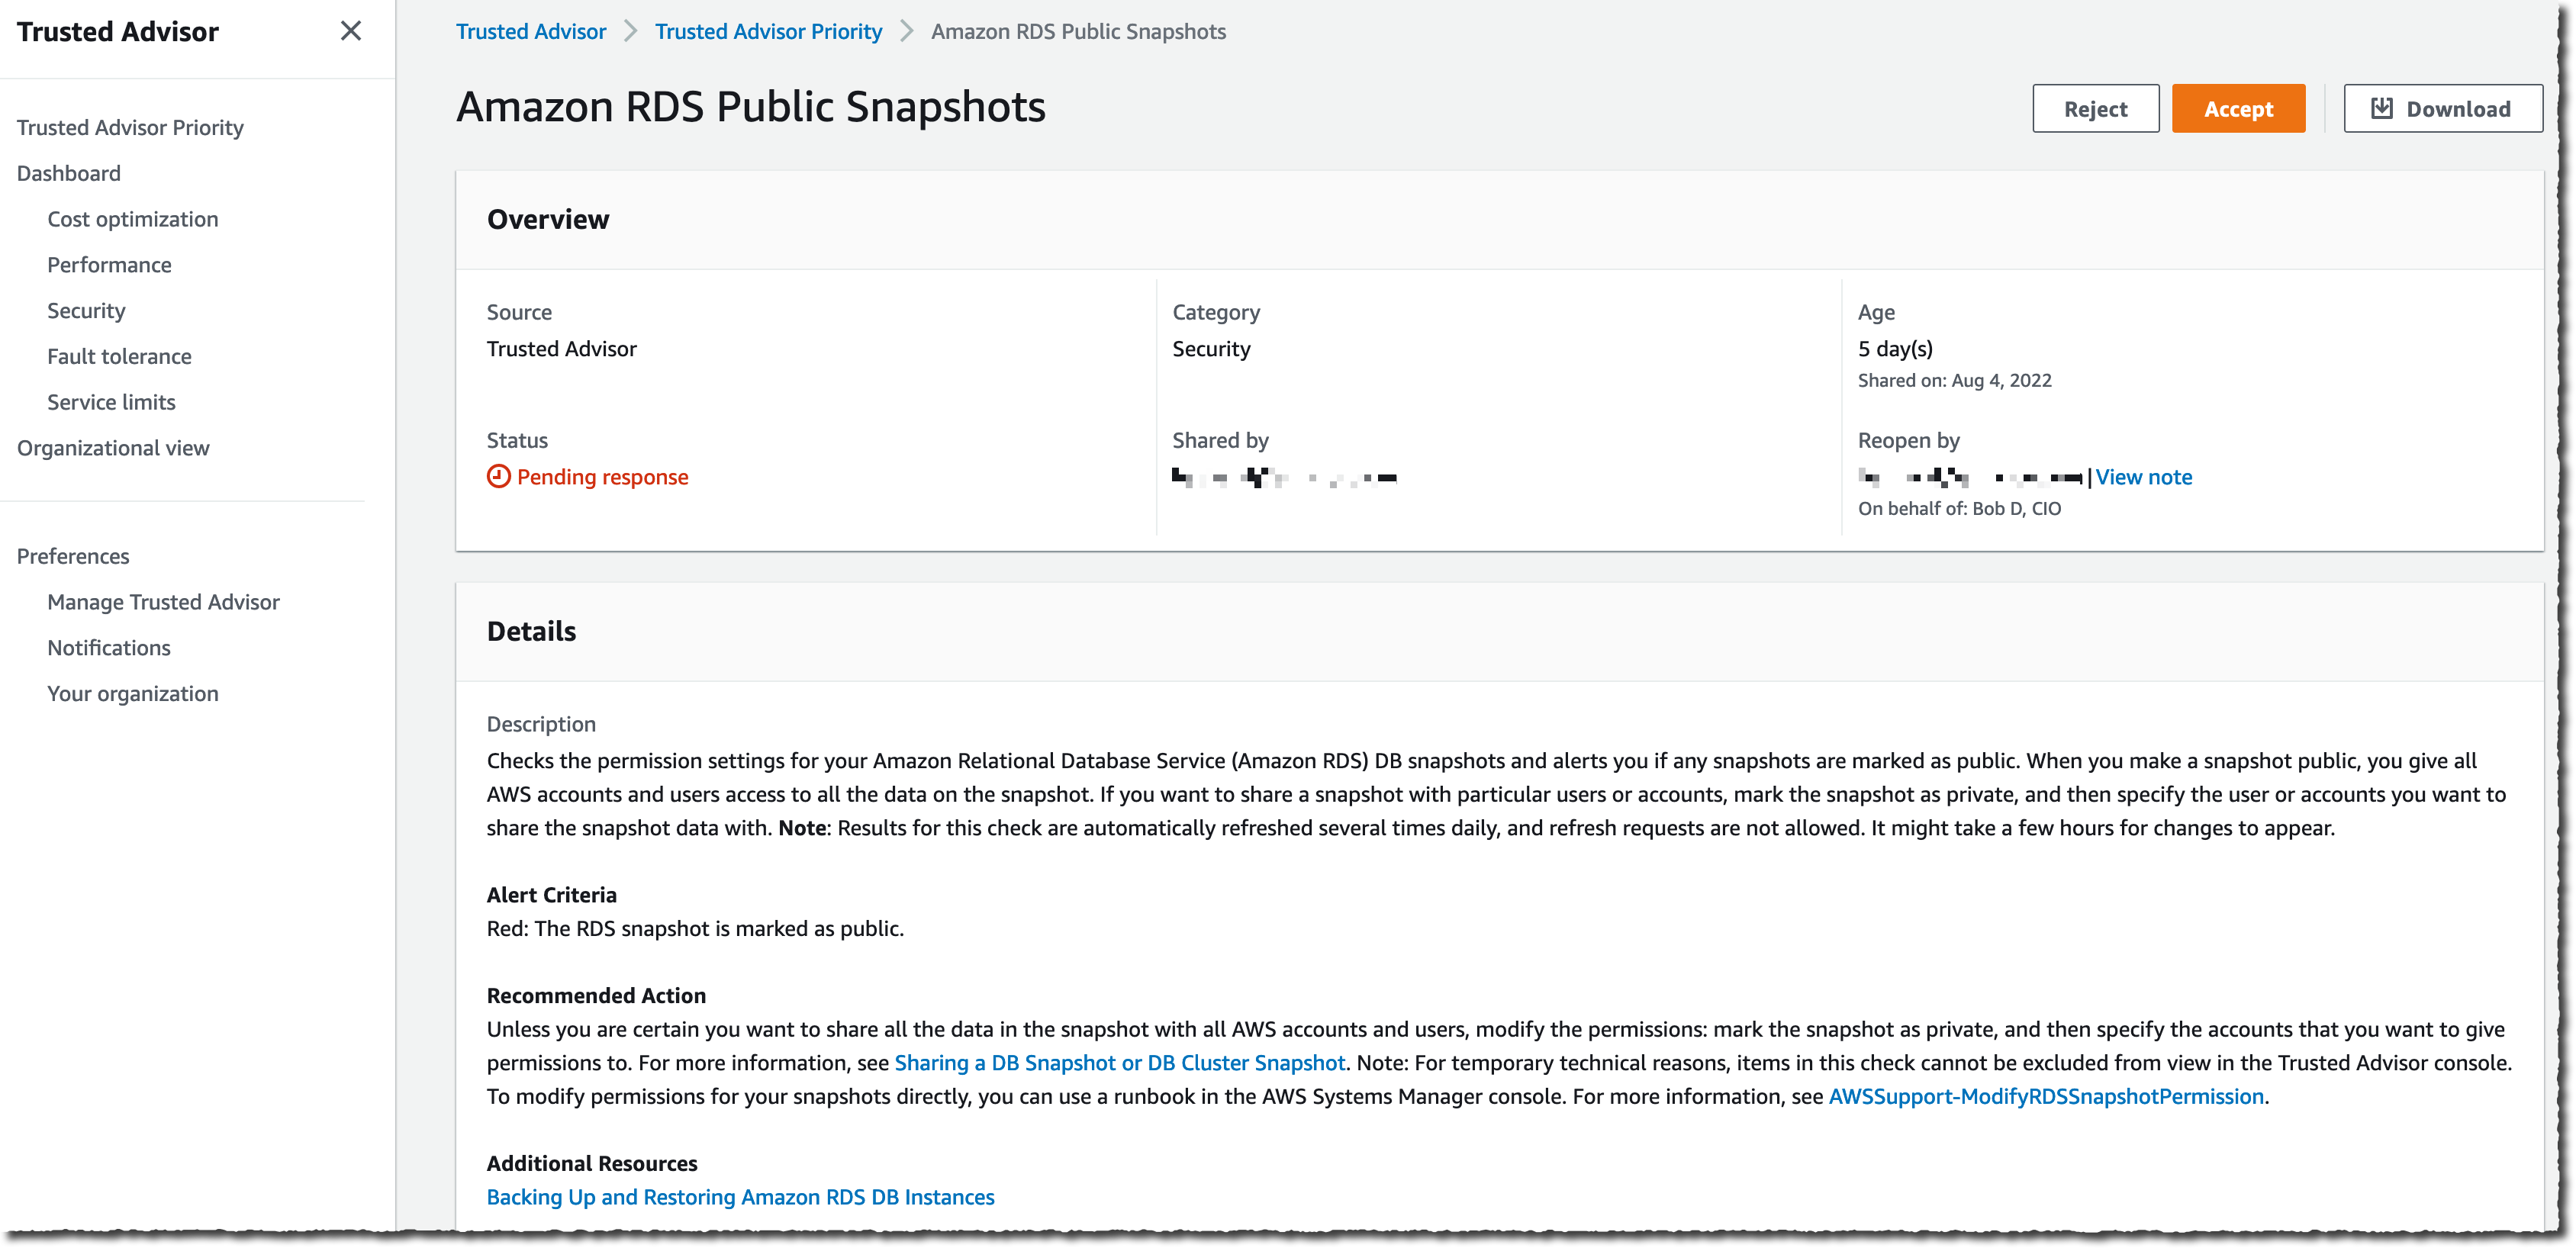
I can select any recommendation to drill down into the details. In this example, I select the second one: Amazon RDS Public Snapshots. This is a recommendation in the Security category.

AWS Trusted Advisor Priority

Recommendations are actionable, and they give you a real course of action to respond to the issue. In this case, it suggests modifying the snapshot configuration and removing the public flag that makes the database snapshot available to all AWS customers.

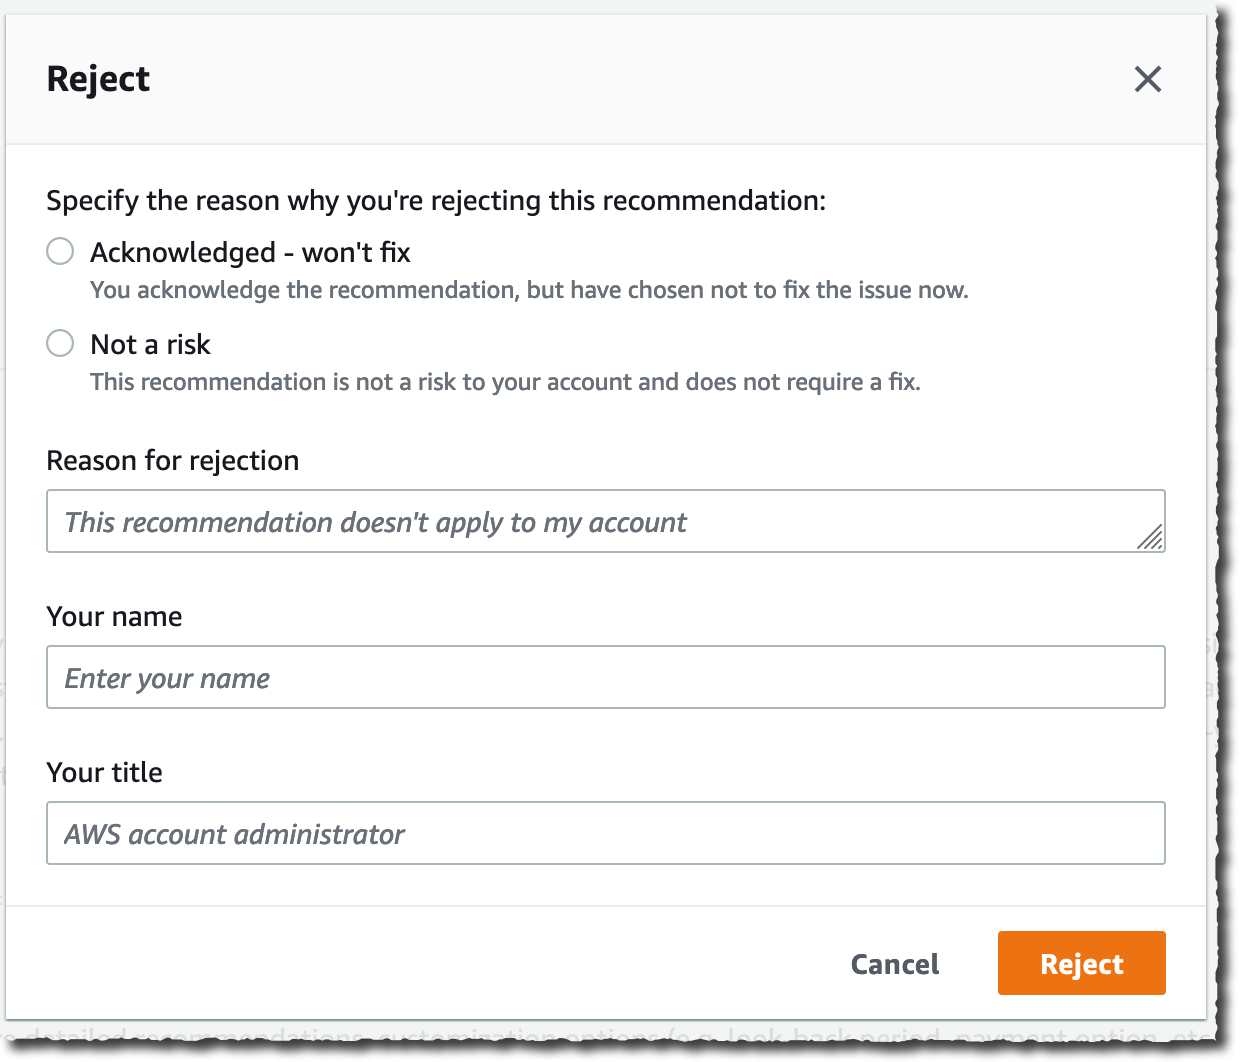
Trusted Advisor Priority provides a closed-loop feedback mechanism where I have the ability to accept or reject a recommendation if I don’t think the issue is relevant to my account.

The information is aggregated at an Organizations level. When you are using Organizations to group accounts to reflect your business units, the recommendations are aggregated and present an overall risk posture across your business units.

As an infrastructure manager, I can either Accept the recommendation and take action or Reject it because it is not a risk or it is something I will not fix and want to remove the recommendation from my list.

AWS Trusted Advisor Priority - Accept AWS Trusted Advisor Priority - Reject

Pricing and Availability
AWS Trusted Advisor Priority is available in all commercial AWS Regions where Trusted Advisor is available now, except the two AWS Regions in China. It is available at no additional cost for Enterprise Support customers.

Trusted Advisor Priority will not replace your Technical Account Manager or Solution Architect. They are key in providing tailored guidance and working with you through all phases of managing your cloud applications. Trusted Advisor Priority provides anytime access to tailored, context-aware, risk-mitigating recommendations and insights from your account team and optimizes your engagement with AWS. It will not reduce your access to your account team in any way but rather will make it easier for you to collaborate with them on your most important priorities.

You can start to use Trusted Advisor Priority today.

And now, go build!

— seb

New row and column interactivity options for tables and pivot tables in Amazon QuickSight – Part 1

Post Syndicated from Bhupinder Chadha original https://aws.amazon.com/blogs/big-data/part-1-new-row-and-column-interactivity-options-for-tables-and-pivot-tables-in-amazon-quicksight/

Amazon QuickSight is a fully-managed, cloud-native business intelligence (BI) service that makes it easy to create and deliver insights to everyone in your organization. You can make your data come to life with rich interactive charts and create beautiful dashboards to share with thousands of users, either directly within a QuickSight application, or embedded in web apps and portals.

In 2021, as part of table and pivot table customization, we launched the ability for authors to resize row height in tables and pivot tables. Now, we are extending this capability to readers, along with other row and column interactions, such as altering column width and header height for both tables and pivot tables using a drag handler, for consistency between row and column interactions and an improved user experience. Apart from the format pane settings, authors can make quick changes to column, row, and header width for both parent and child nodes by simply dragging the cell, column, or row to the desired setting using the drag handler.

The following are the different interactions that both readers and authors can perform, some of which were already available for tables.

Modify row height

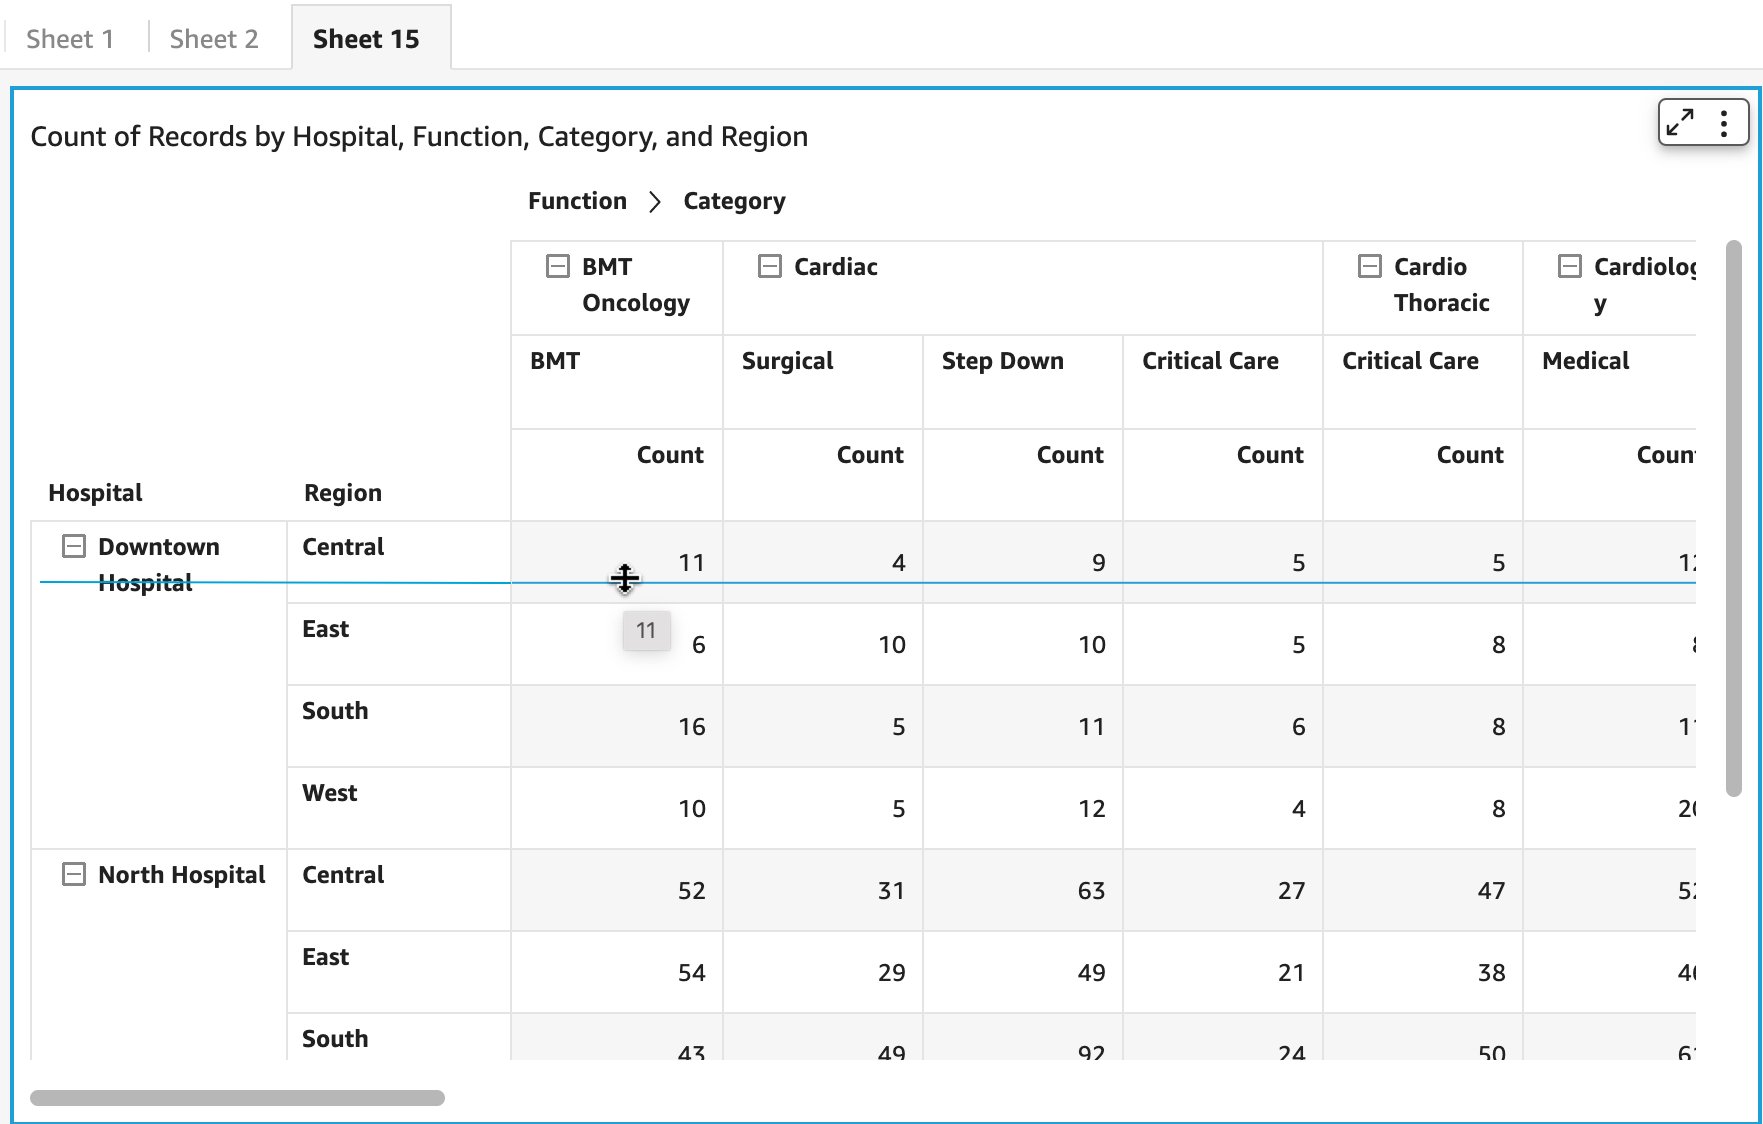
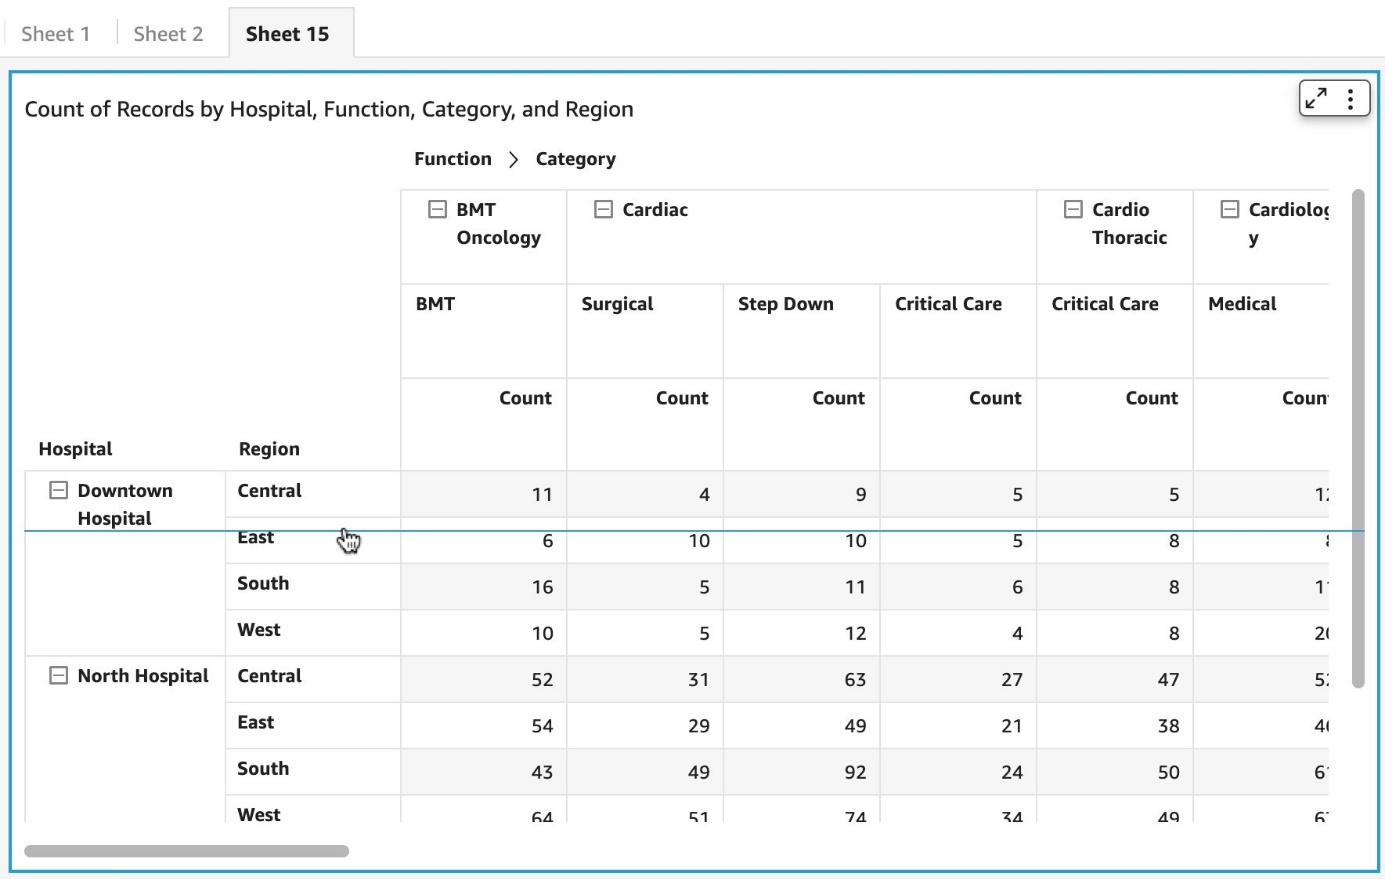
You can modify row height using the drag handler for cells, row headers, or column headers.

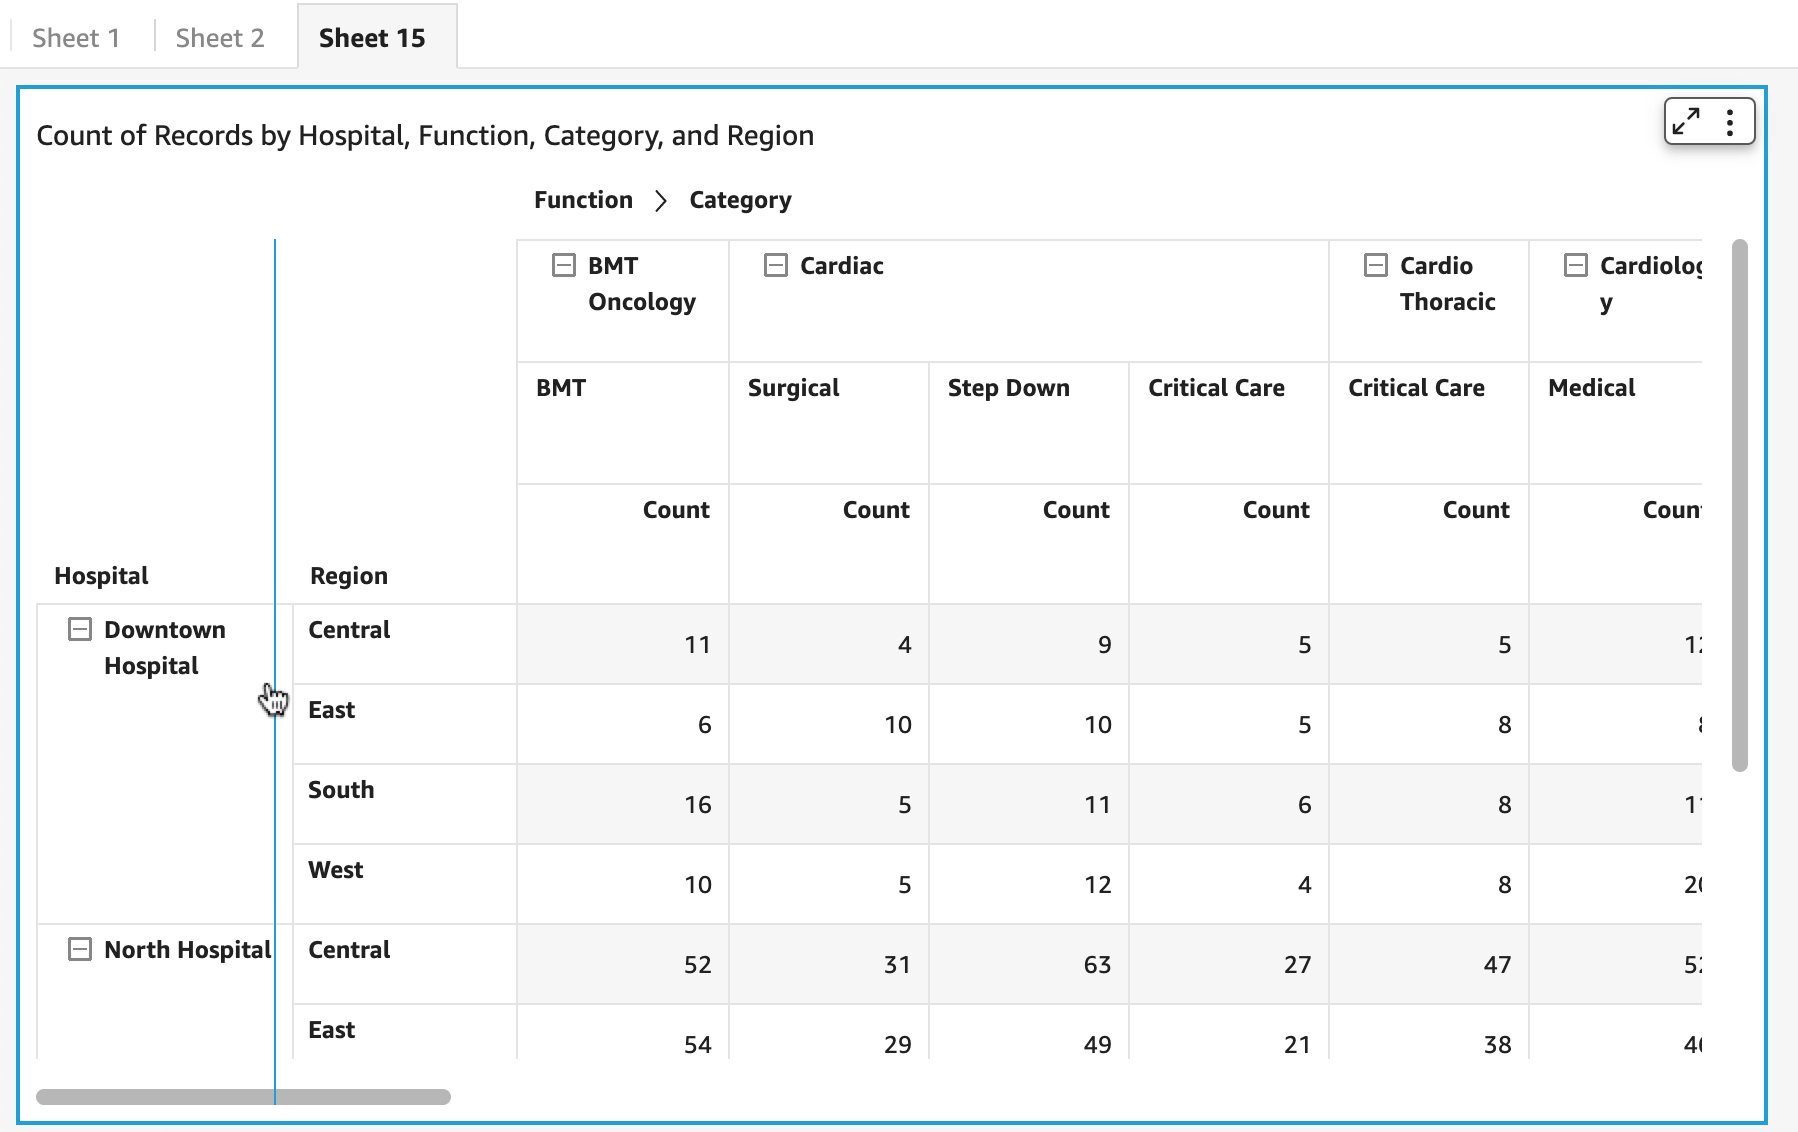
The following screenshot illustrates how to alter the row height by dragging from any cell in the table or pivot table.

For row headers, you can only resize row height by dragging the last element (child node), which gets aggregated to define the row height for the parent node.

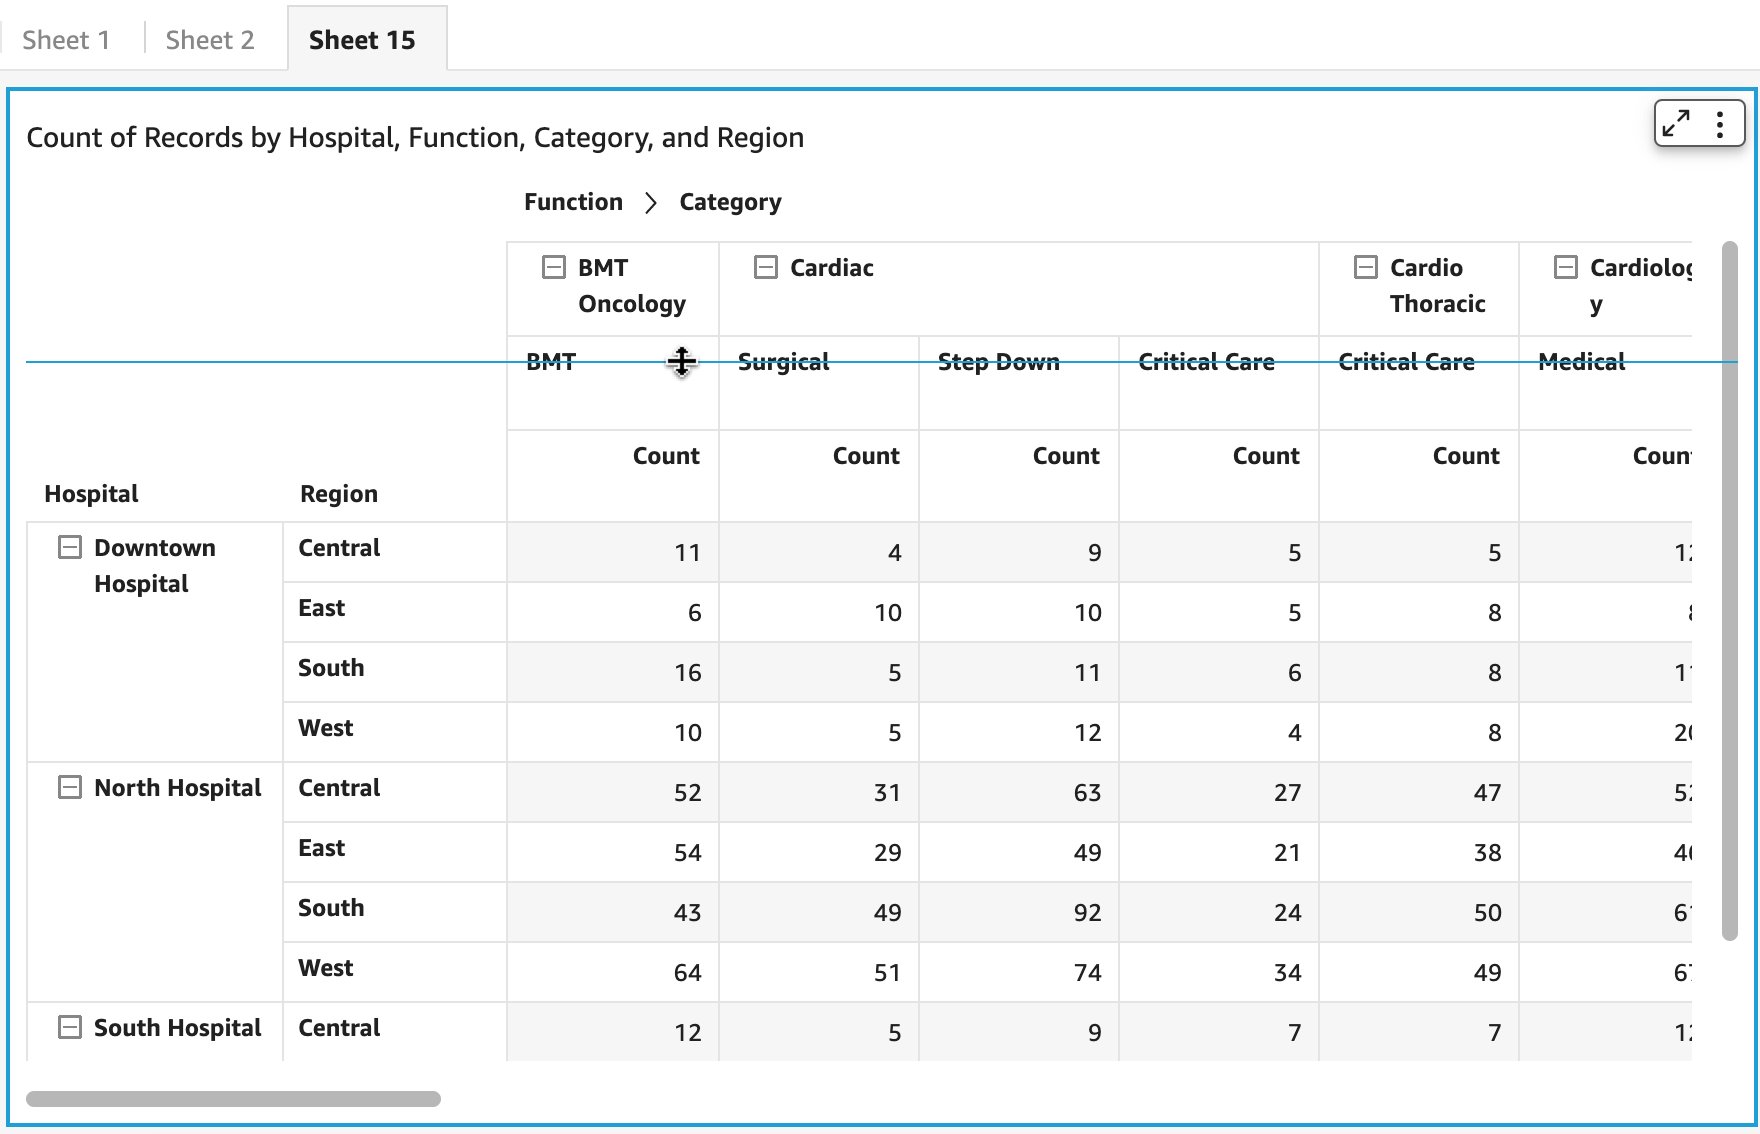
You can resize the height of the column headers at any level such that you can have different heights at each level for better aesthetics.

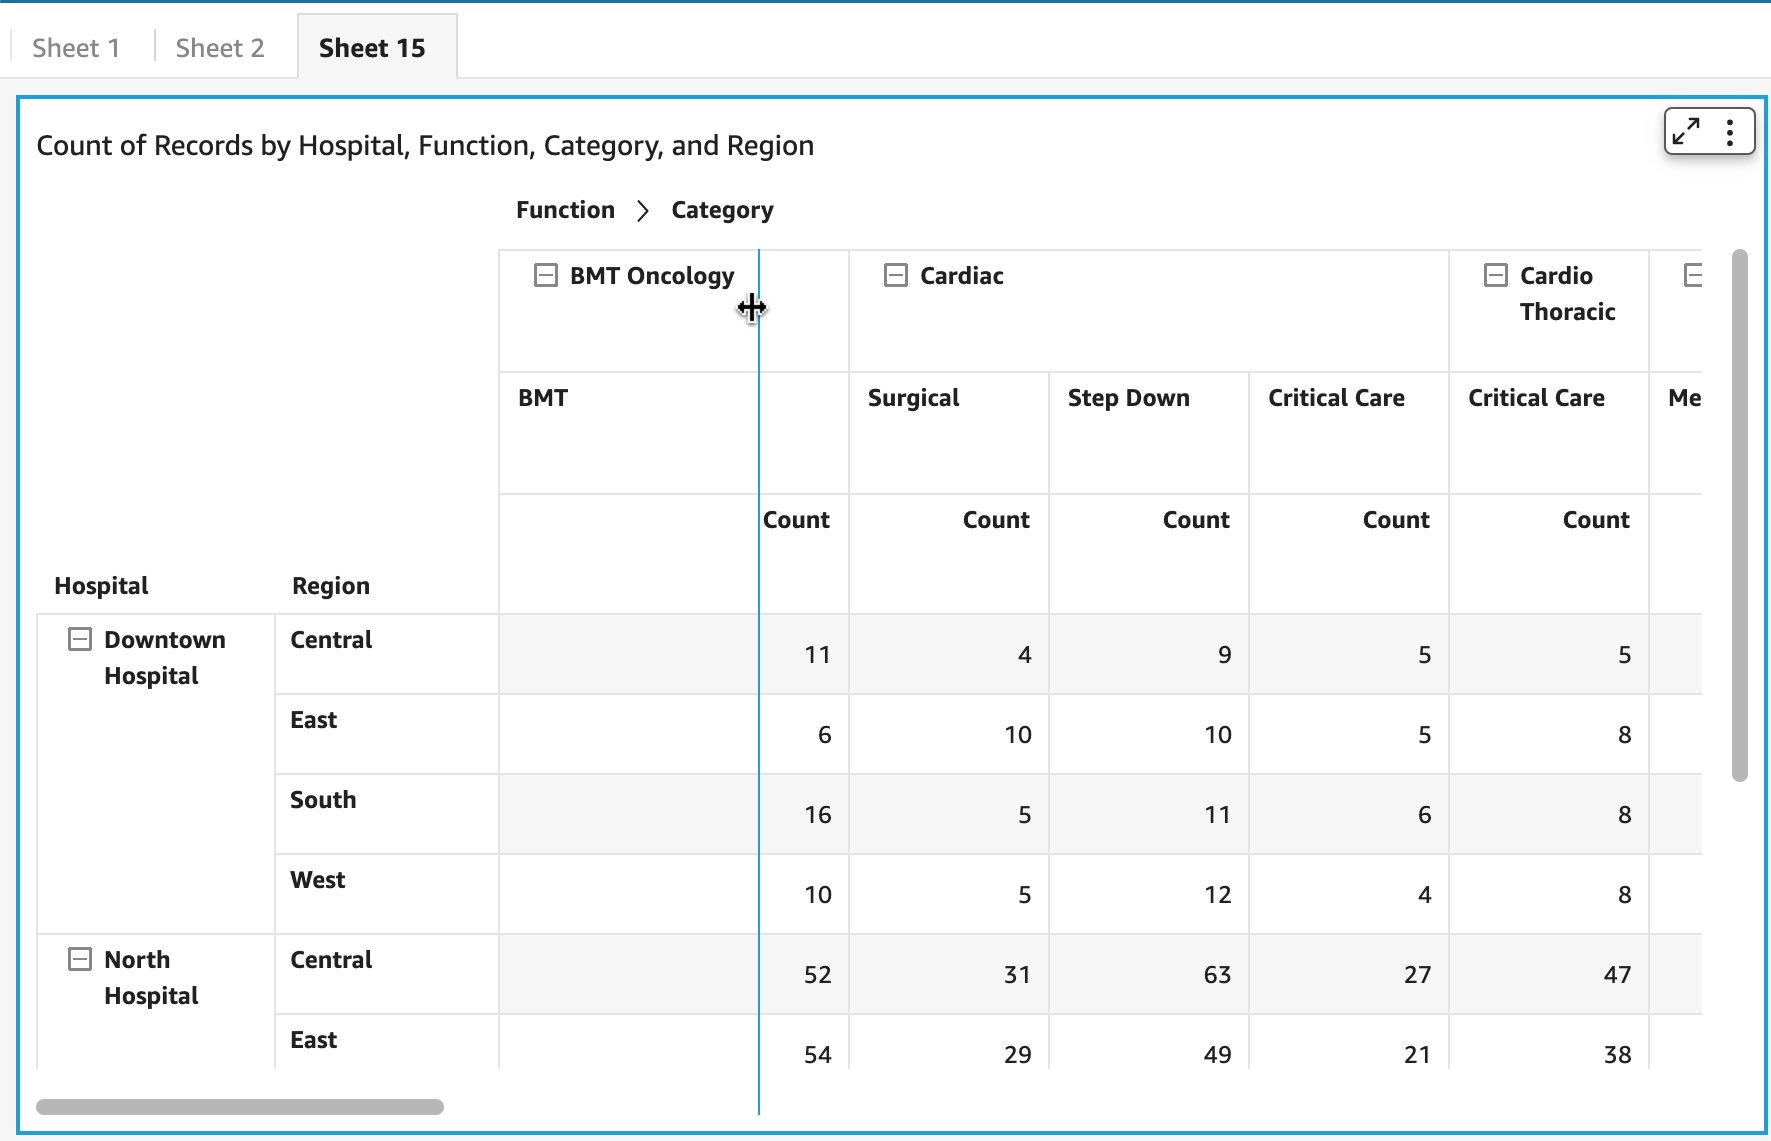
Modify column width

You can also use the drag handler to modify column width for row headers, column headers, or cells.

You can alter column width for any field assigned to rows, as shown in the following screenshot.

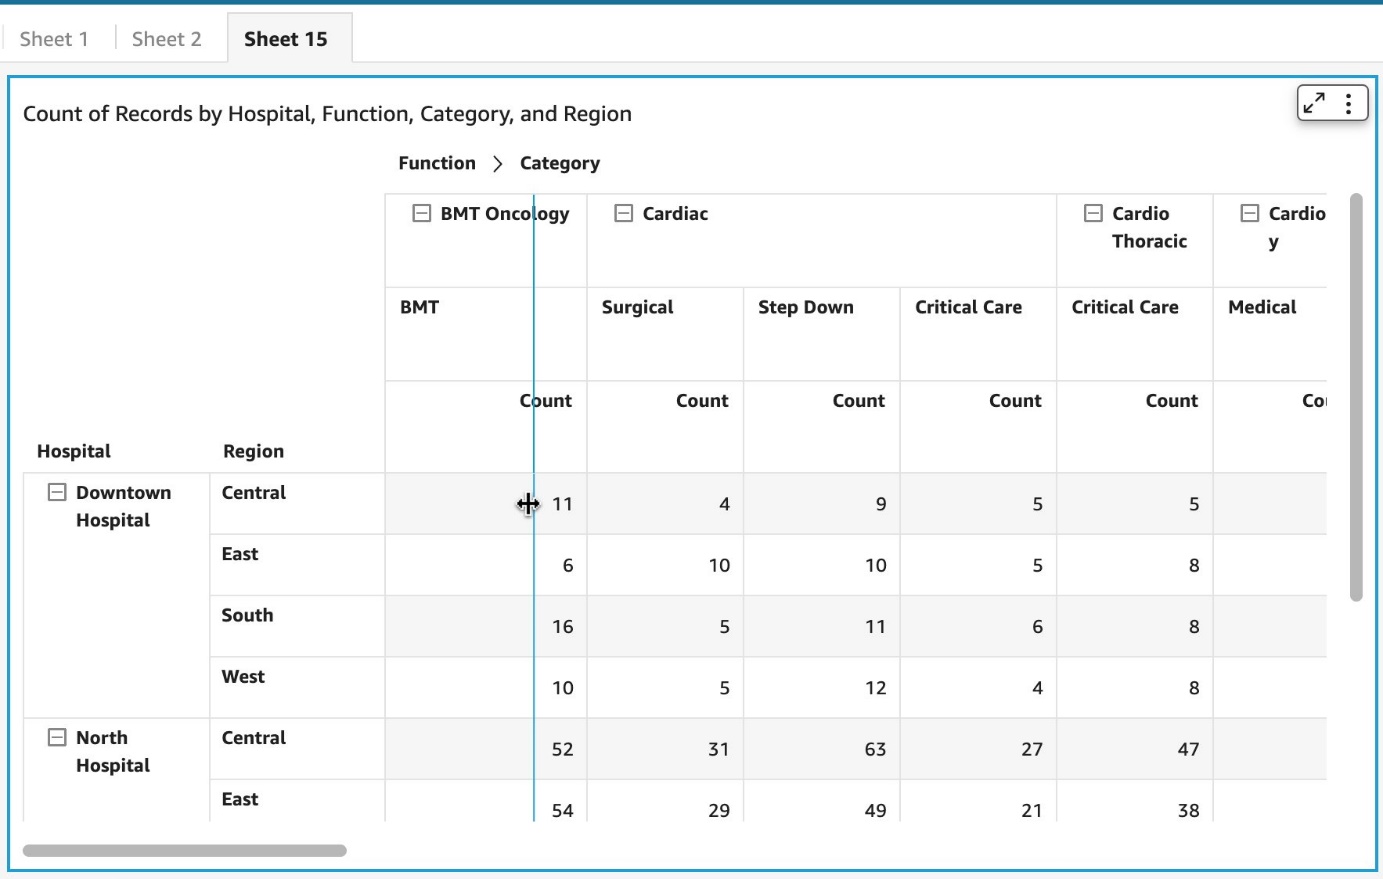
You can alter column width for column dimension members both from the parent or leaf node in the case of hierarchy, or column field or values headers in the absence of a column hierarchy.

You now have complete flexibility to resize column width from cells. Depending on which cell, the corresponding column width is adjusted.

Considerations

A few things to note about this new feature:

  • Drag handlers are available for both web and embedded use cases
  • Row height is set in common for all rows and not specific to a particular row

Summary

With the introduction of a drag handler, authors and readers can now quickly alter column width, row height, and header height for tables and pivot tables. This provides a consistent behavior and improved user interaction for both the personas and visuals. To learn more about table and pivot table formatting options, refer to Formatting tables and pivot tables in Amazon QuickSight.

Try out the new feature and share your feedback and questions in the comments section.


About the author

Bhupinder Chadha is a senior product manager for Amazon QuickSight focused on visualization and front end experiences. He is passionate about BI, data visualization and low-code/no-code experiences. Prior to QuickSight he was the lead product manager for Inforiver, responsible for building a enterprise BI product from ground up. Bhupinder started his career in presales, followed by a small gig in consulting and then PM for xViz, an add on visualization product.

Leading the Way in Tampa

Post Syndicated from Julian Waits original https://blog.rapid7.com/2022/08/17/leading-the-way-in-tampa/

Leading the Way in Tampa

If you’ve been to the Tampa Bay area in recent years, you’ve probably noticed the significant tech industry expansion taking place in the Channel District. It’s an exciting time to be a part of the scene, and Rapid7 is smack in the middle. Being active in the Tampa Bay Chamber of Commerce is incredibly rewarding. I’ve personally been involved with the Chamber for more than a year, and I’ve witnessed first-hand their commitment to making Tampa Bay a vibrant, inclusive place to do business.

My next adventure with the Chamber involves becoming a part of its Leadership Tampa program — one of the oldest leadership programs in the country — which fulfills a mission to highlight the strengths of the Tampa Bay region and impact the community through various organized projects. Our 52-person group will also be collaborating with local not-for-profits to create strength in numbers.

We will continue building upon the diversity and inclusion efforts driven by previous Leadership Tampa members, as well as focus on the challenges of transportation, affordable housing, and inflation, among others. I’m looking forward to the many conversations and activities we will undertake as part of this initiative.

NEVER MISS A BLOG

Get the latest stories, expertise, and news about security today.

Additional reading:

The collective thoughts of the interwebz