All posts by Sébastien Stormacq

Runtime instances: persistent compute for production AI agents on Amazon Bedrock AgentCore

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/runtime-instances-persistent-compute-for-production-ai-agents-on-amazon-bedrock-agentcore/

When you move AI agents from prototype to production, the infrastructure challenges multiply. Your agents need to persist state across multi-step workflows that run for hours or days. They need to coordinate with other agents, share context, and sometimes access GPUs for specialized tasks. Amazon Bedrock AgentCore runtime microVMs provide a fully managed environment for invocations that can run for up to 8 hours and support stateful workflows through managed session storage. Some workloads also benefit from dedicated, larger-capacity environments — for example, when agents need to run continuously for multiple days, access GPUs or the underlying OS, or run multiple collaborating agents on the same host.

Today, I’m happy to announce runtime instances, a new complementary compute option in Amazon Bedrock AgentCore Runtime that gives your agents persistent, managed infrastructure purpose-built for complex agent workloads.

What you get
Runtime instances provides AWS-managed EC2 infrastructure where you deploy multiple agents in a single runtime, each with their own dependencies and artifact types. Your agents can collaborate on the same host within shared sessions that persist for up to 14 days. The service supports GPU acceleration for compute-intensive tasks, session stop/restart to save costs during idle periods, and containerized deployments for teams that want to ship independently. For knowledge that needs to survive beyond a session, runtime instances pairs naturally with Amazon Elastic Block Store (Amazon EBS) and AgentCore Memory, which gives your agents long-term recall across sessions and environments.

Before today, if you wanted to keep your agents running for days or they needed GPU access, or multi-agent coordination, you had to build and manage that infrastructure yourself. You provisioned EC2 instances, configured networking, set up session management, handled scaling, and stitched together monitoring. Runtime instances handles all of that for you while integrating with the same AgentCore APIs, identity controls, and observability you already use with AgentCore Runtime microVMs.

A few things that should make agent developers smile: your agents can call each other as tools within a shared session, iterating autonomously until the job is done. You bring any framework (CrewAI, LangGraph, LlamaIndex, Strands) and any model. Packaging is minimal, a @app.entrypoint decorator and a zip file or container image. And if your workflow spans days, hibernate Monday night and resume Wednesday morning with everything intact.

Runtime microVMs and runtime instances are complementary compute options that you can use independently or together through the same AgentCore runtime APIs. A lightweight orchestrator agent on runtime microVM can coordinate and dispatch work to specialized worker agents running on instances. The orchestrator handles API calls, task routing, and result aggregation using runtime microVM’s fast scaling, while workers on Instances perform compute-intensive tasks like code compilation, security scanning, or GUI automation that require persistent state and direct OS access.

Let me show you how it works
I built two agents for this demo: a code writer agent that generates Python code from natural language descriptions, and a code reviewer agent that analyzes the generated code for bugs, security issues, and style improvements. Both agents share the same file system, so the reviewer can read whatever the writer produces without any data transfer or API calls between them.

Here is the code writer (simplified, no error handling):

writer = Agent(
    model="us.anthropic.claude-sonnet-4-5-20250929-v1:0",
    system_prompt=(
        "You are a senior Python engineer. "
        "Given a task, return ONLY a single Python code block — no prose."
    ),
)

@app.entrypoint
def handler(event, context):
    task = event.get("task") or event.get("prompt")
    session_id = getattr(context, "session_id", None) or event.get("session_id")
    session_dir = SHARED_DIR / session_id
    session_dir.mkdir(parents=True, exist_ok=True)

    code = str(writer(task))
    (session_dir / "code.py").write_text(code)

    return {"agent": "writer", "wrote": str(session_dir / "code.py"), "code": code}

Here is the code reviewer agent (simplified, no error handling):

reviewer = Agent(
    model="us.anthropic.claude-sonnet-4-5-20250929-v1:0",
    system_prompt=(
        "You are a strict Python code reviewer. "
        "Given code, return 3 bullet points: bugs, style, suggestions."
    ),
)

@app.entrypoint
def handler(event, context):
    session_id = getattr(context, "session_id", None) or event.get("session_id")
    code_path = SHARED_DIR / session_id / "code.py"
    code = code_path.read_text()
    review = str(reviewer(f"Review this code:\n\n{code}"))

    return {"agent": "reviewer", "read": str(code_path), "review": review}

Each agent is a Python application using Strands Agents with an @app.entrypoint decorator and a model of its choice. I package each one as a zip file. For this demo, I use the AWS Management Console. You can also use the AgentCore CLI, the AWS Command Line Interface (AWS CLI) or infrastructure as code.

Step 1: Create a capacity provider.

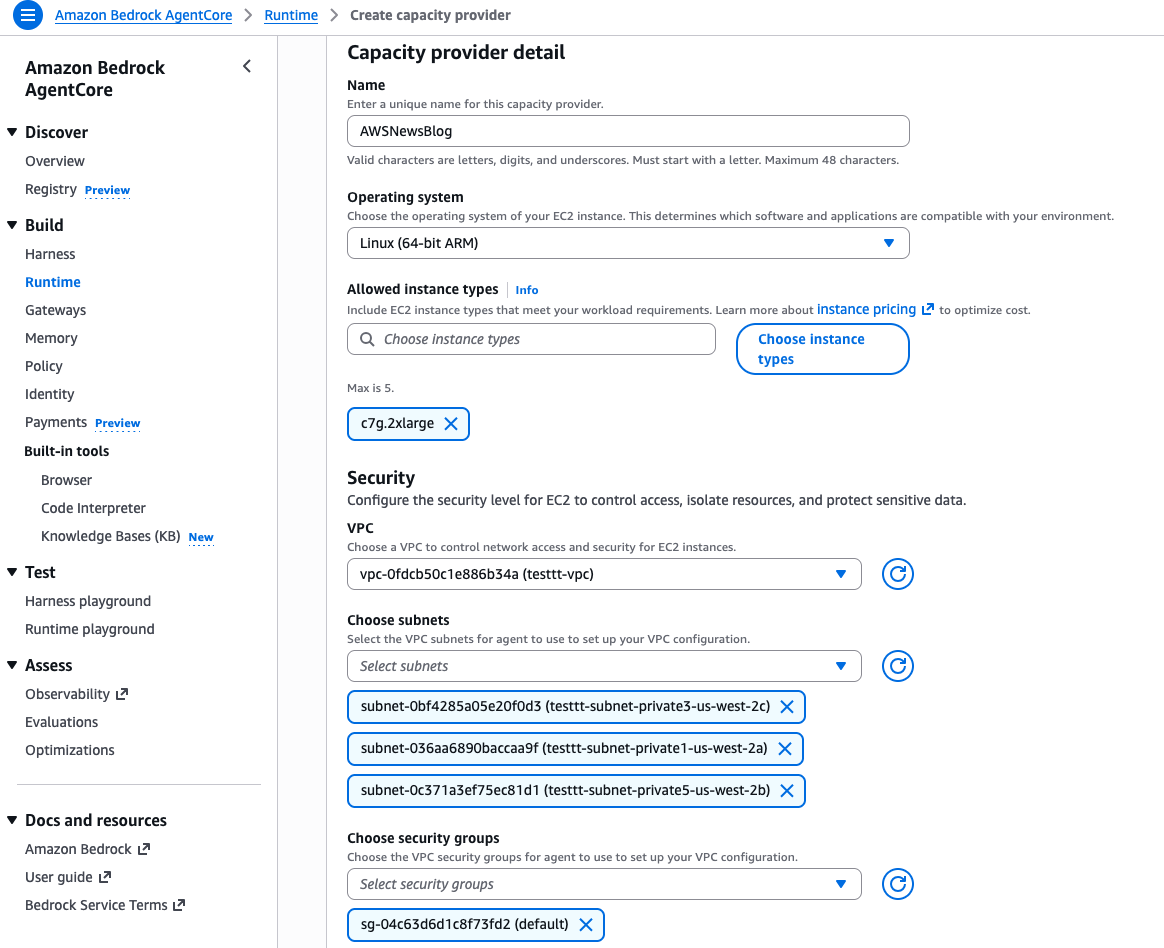
A capacity provider defines the EC2 infrastructure your agents run on. In the AgentCore console, I select Runtime in the left navigation, then select the Capacity providers tab and Create capacity provider.

ACI Create Capcity Provider 1

I give it a Name, select Linux (64-bit ARM) as the Operating system, and choose c7g.2xlarge as the Allowed instance types. This gives me 8 vCPUs and 16 GiB of memory, enough for both agents to run comfortably side by side.

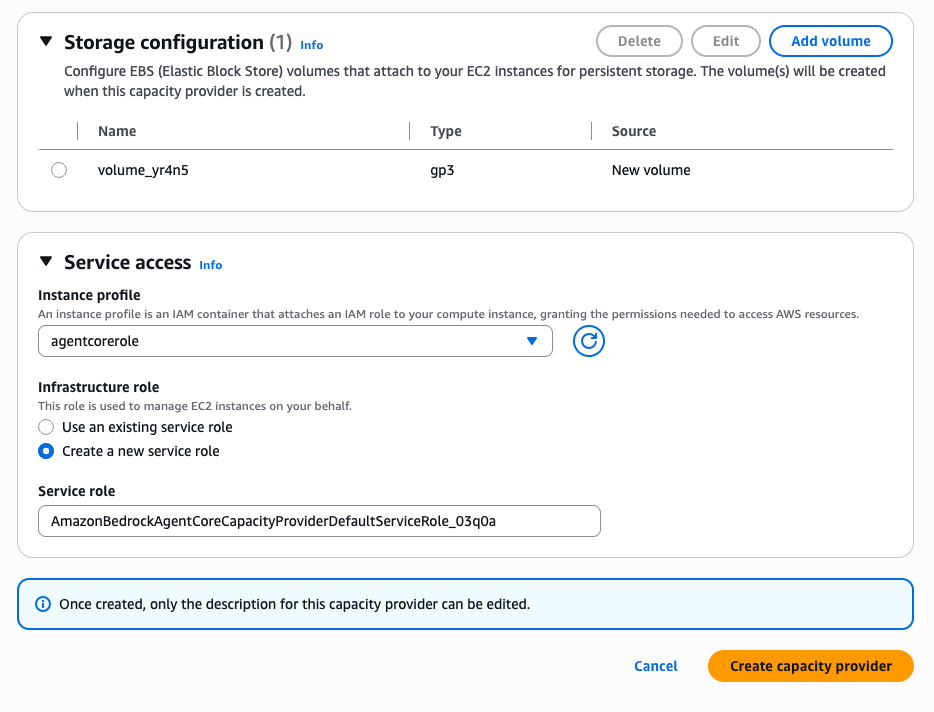
Further down, I configure the VPC, subnets, and security groups for network access. Under Storage configuration, I keep the default gp3 volume. Under Service access, I select Create a new service role and let the console create the infrastructure role that manages EC2 instances on my behalf.

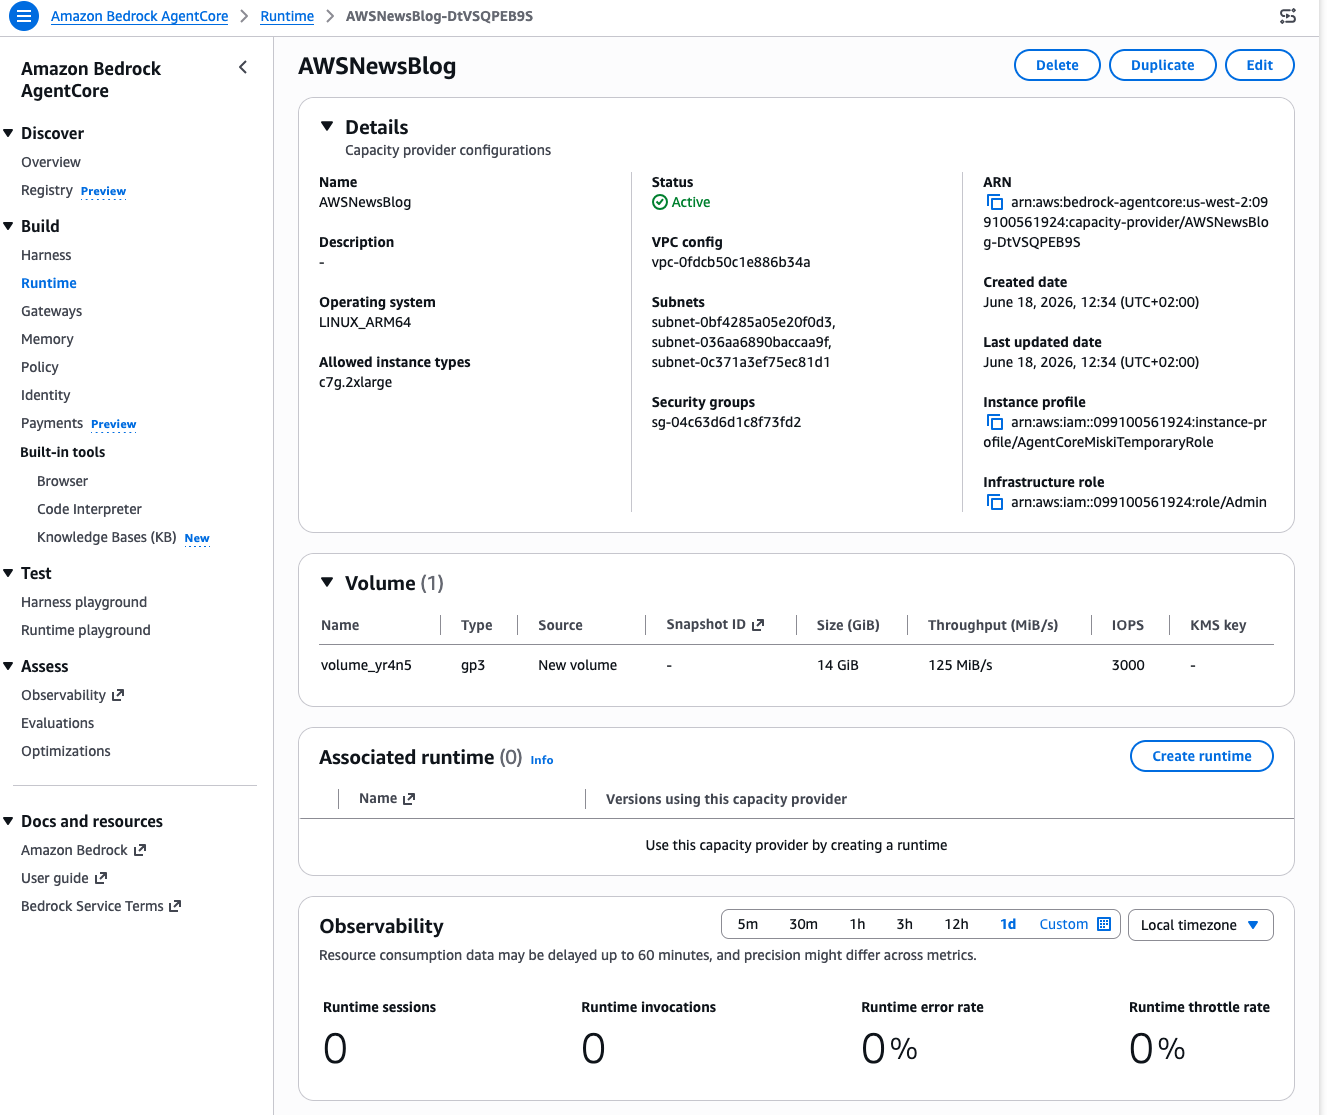
I select Create capacity provider and wait a few seconds. The status moves to Active.

ACI Create Capacity Provider 2

ACI Create Capacity Provider 3

Note the capacity provider configuration summary: operating system, instance type, subnets, security group, instance profile, and infrastructure role. Once created, only the description can be edited, so verify your settings before you proceed.

ACI Create Capcity Provider 2

Step 2: Create a runtime and deploy the first agent.

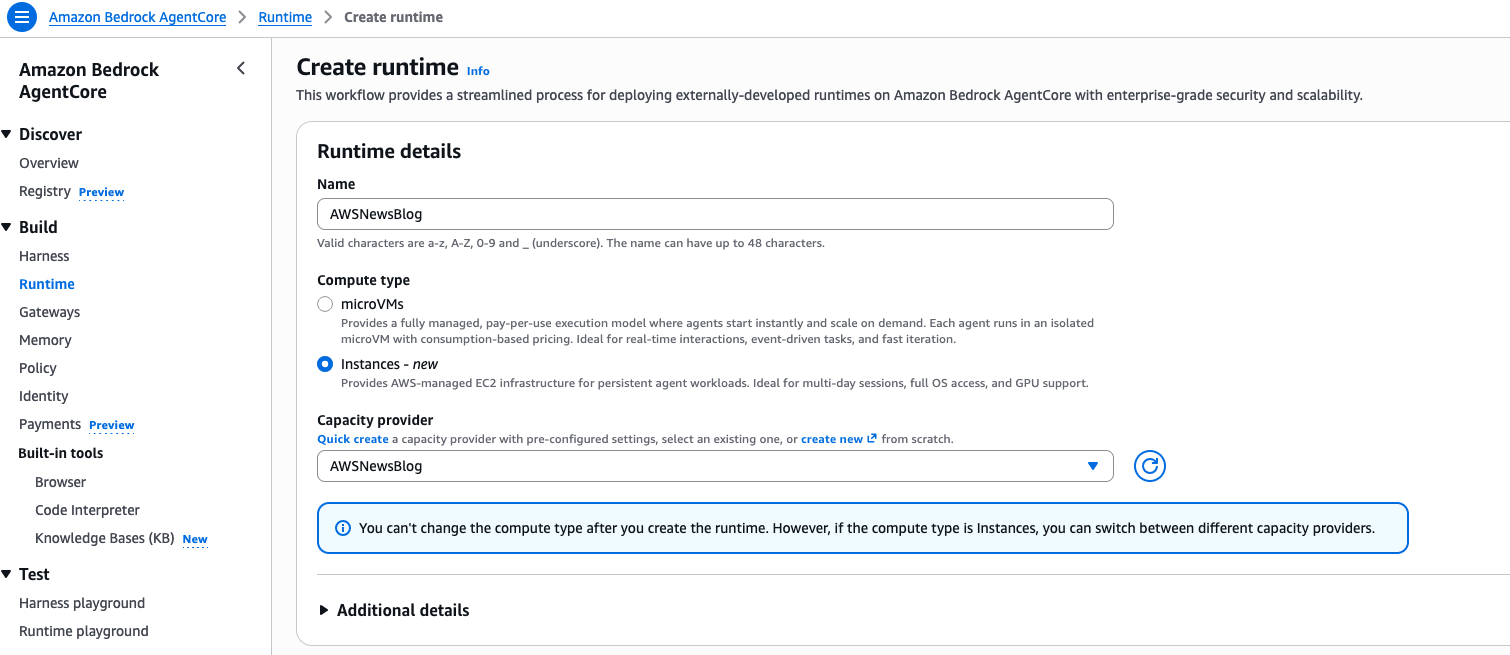
Back on the Runtime page, I select Create runtime. I give it a Name, select Instances as the Compute type, and choose the Capacity provider I created in the previous step.

ACI Create Runtime 1

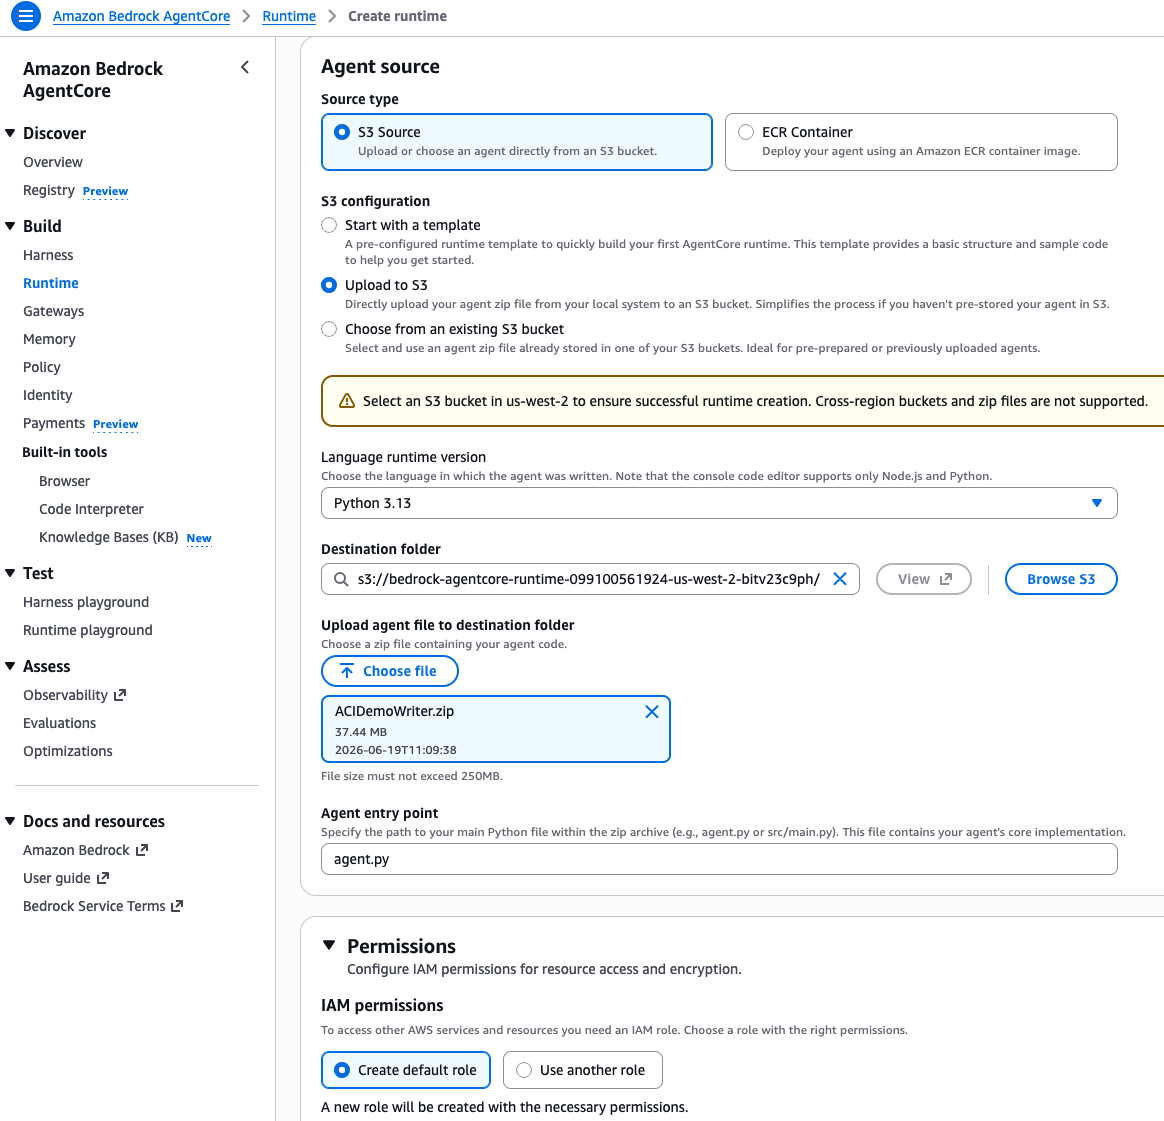
Under Agent source, I select S3 Source, then Upload to S3. I choose my agent zip file (ACIDemoWriter.zip), set the Language runtime to Python 3.13, and specify agent.py as the Agent entry point. This is the file that contains my @app.entrypoint decorated function. Under Permissions, I select Create default role to let the console provision the IAM role my agent needs.

ACI Create Runtime 2

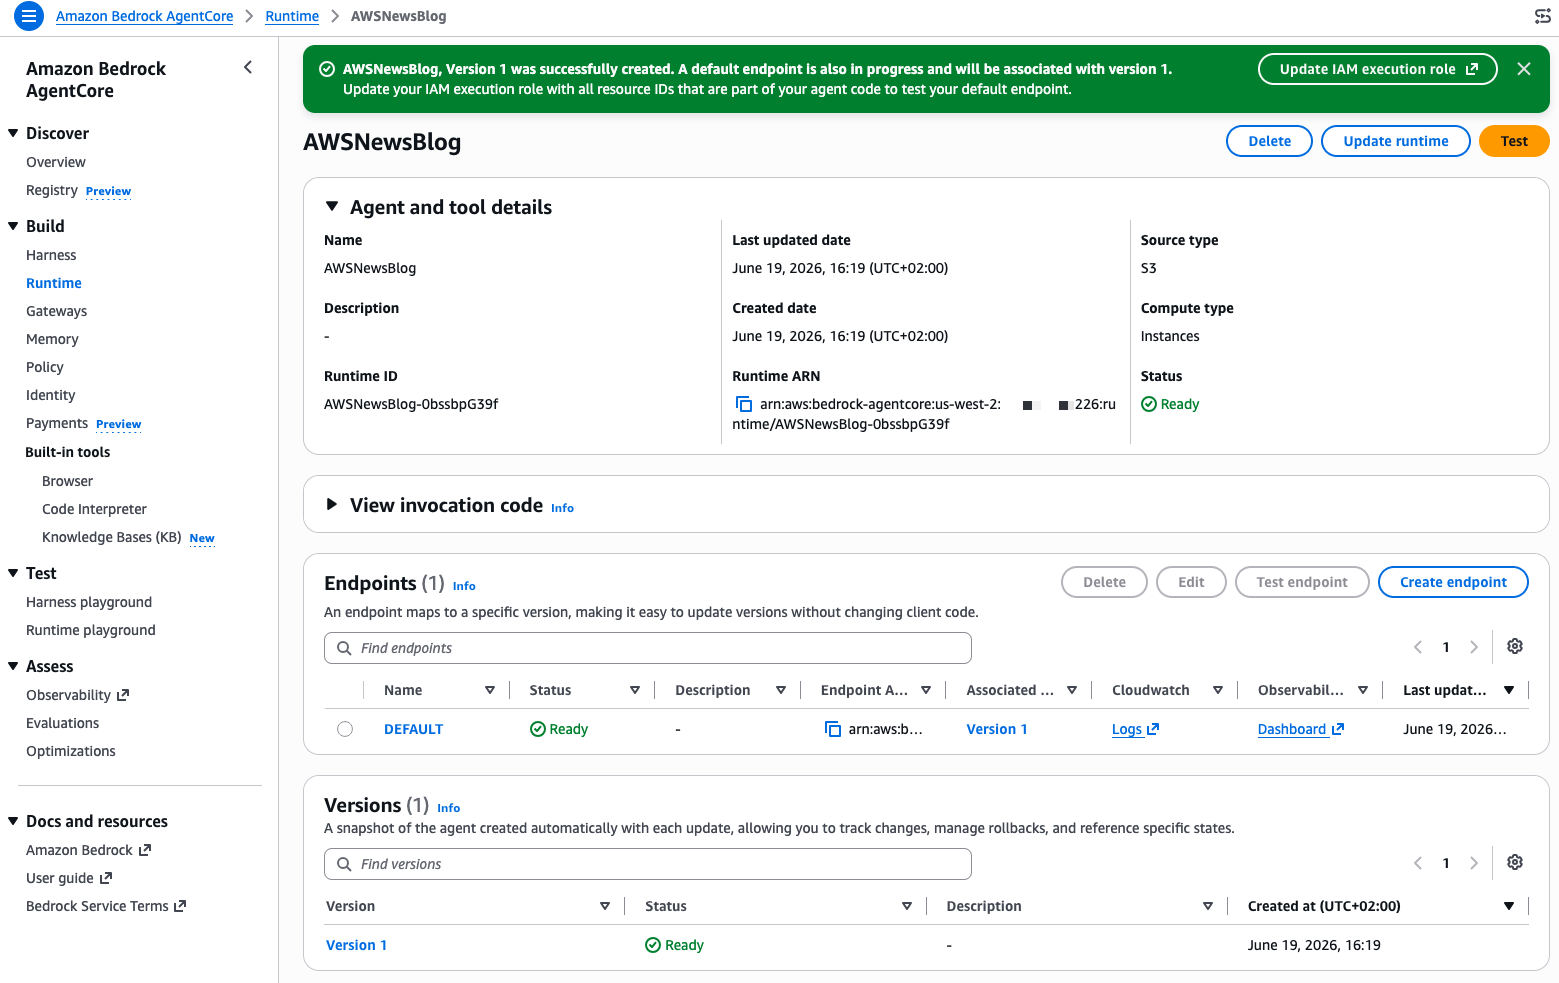
I select Create runtime and wait for the status to become Ready.

I repeat the same process for my code reviewer agent. I create a second runtime, select the same capacity provider, upload my reviewer agent zip file, and wait for it to become Ready. Both agents now share the same underlying EC2 infrastructure.

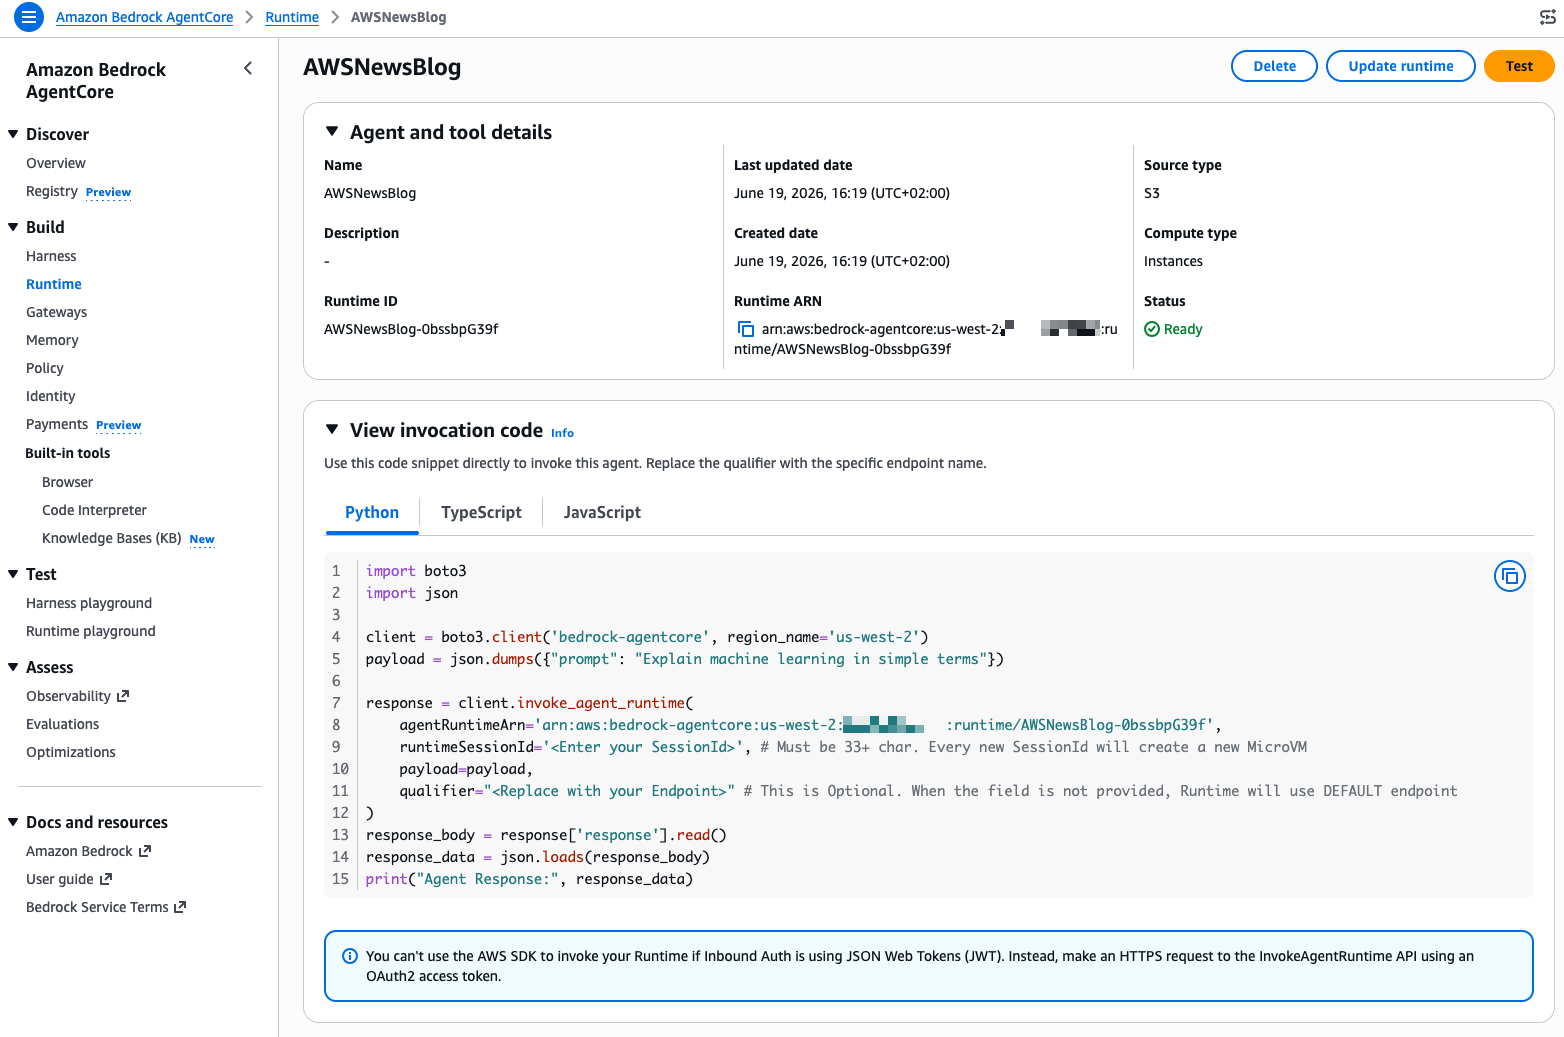
AgentCore Runtime Instances - Agent ReadyThe console shows me a View invocation code section with ready-to-use Python, TypeScript, and JavaScript snippets to invoke my agent programmatically. But for this demo, I use the built-in test feature. I select Test on the writer agent’s page.

AgentCore Runtime Instances - Show invocation codeStep 3: Invoke agents and observe collaboration.

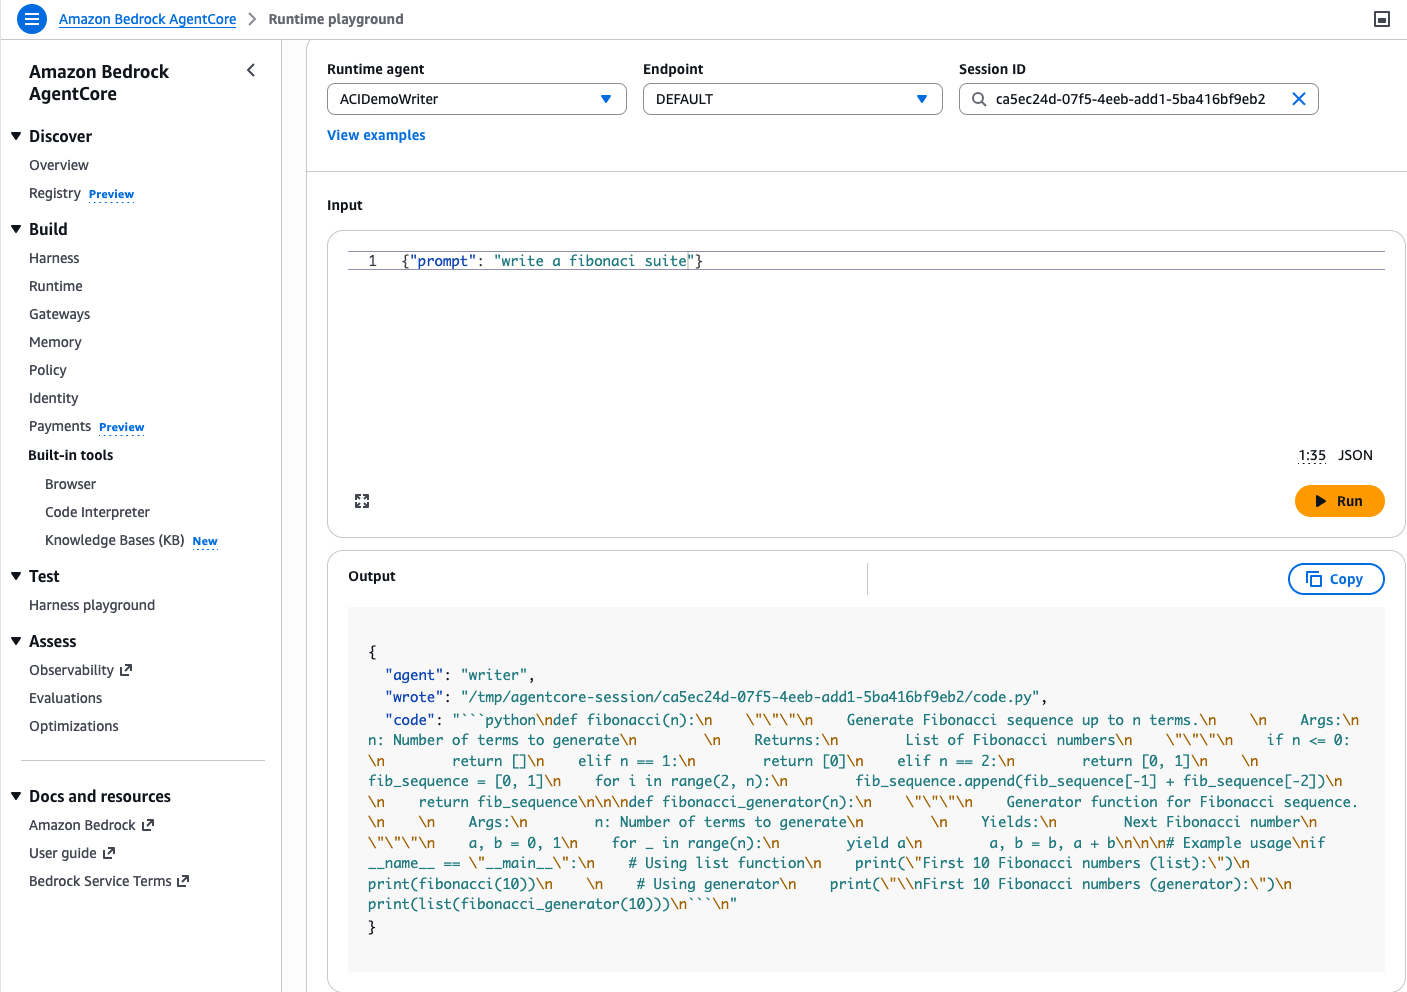
The Runtime playground opens. At the top, I see three fields: Runtime agent, Endpoint, and Session ID. The console generates a session ID automatically. I take note of it because I will reuse it with the reviewer agent.

In the Input field, I type a JSON payload asking the writer agent to generate code:

{"prompt": "write a fibonacci suite"}

I select Run. After a few seconds, the Output panel shows the agent’s response. The writer agent generated a Python module with two implementations of a Fibonacci sequence (a list-based function and a generator) and wrote it to /tmp/agentcore-session/ca5ec24d-07f5-4eeb-add1-5ba416bf9eb2/code.py. Notice the session ID in the file path. That directory is the shared file system for this session.

AgentCore Runtime Instances - Invoke code writer agent

Step 4: Invoke the reviewer agent in the same session.

Now I switch the Runtime agent dropdown to ACIDemoReviewer. The important part: I paste the same session ID (ca5ec24d-07f5-4eeb-add1-5ba416bf9eb2) in the Session ID field. This is what connects the two agents.

I type a simple prompt:

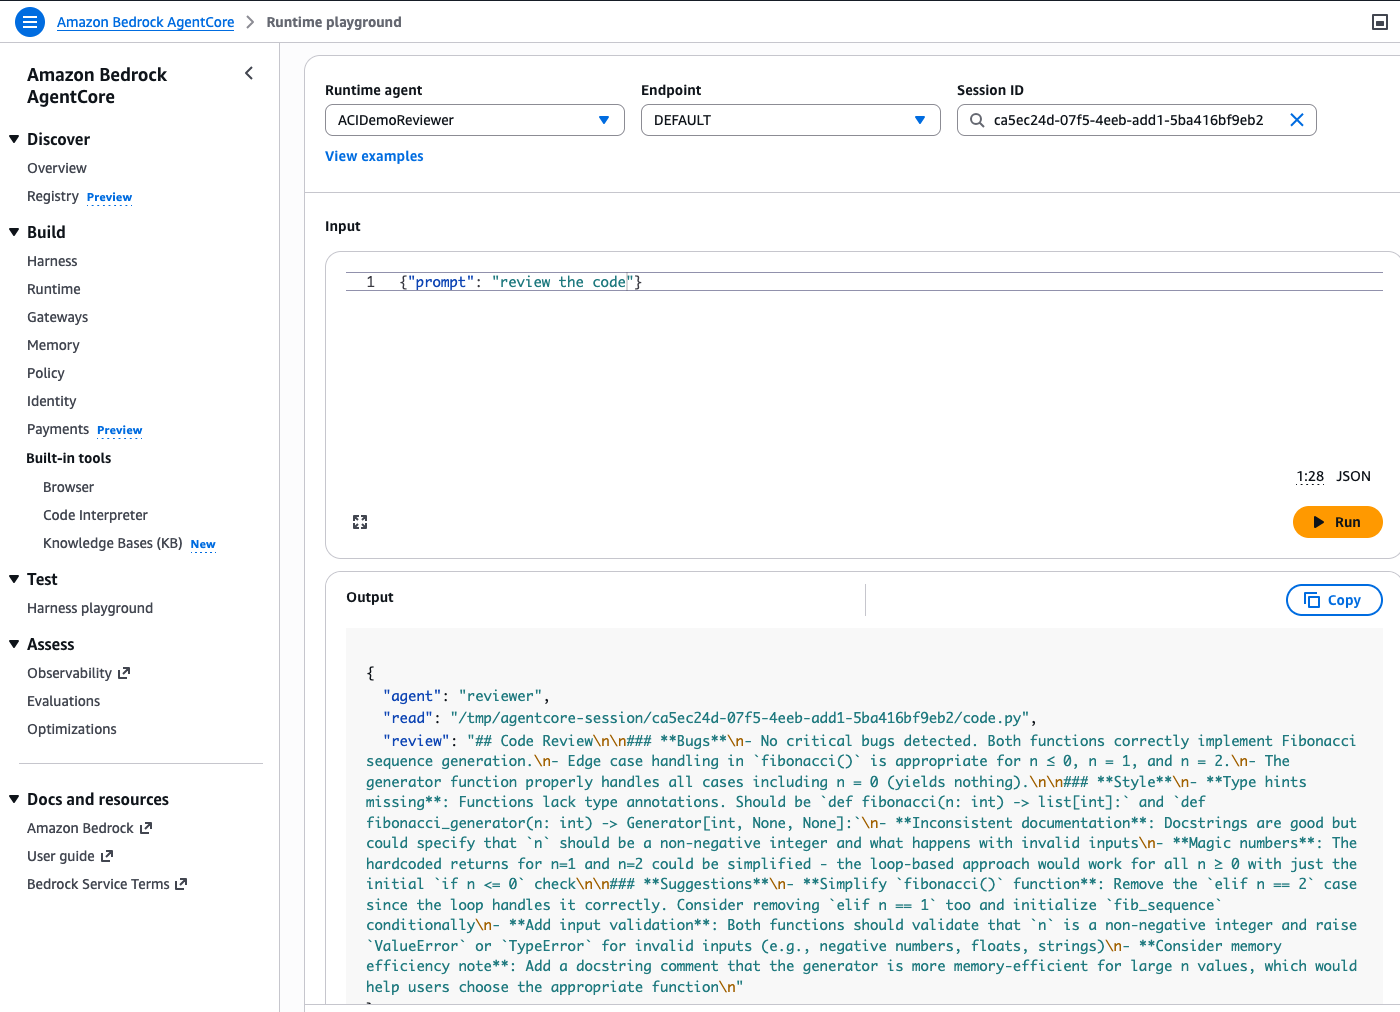
{"prompt": "review the code"}

I select Run. The reviewer agent reads the file the writer produced from the shared session directory and returns a detailed code review. It finds no critical bugs but suggests adding type hints, input validation, and simplifying the edge case handling.

AgentCore Runtime Instances - Invoke code reviewer agentThe two agents never exchanged messages or called each other’s APIs. They collaborated through the shared file system that runtime instances provide within a session. You can extend this pattern to any number of agents: a test agent that runs the code, a documentation agent that generates README files, a security agent that scans for vulnerabilities, all sharing the same working directory.

Key details
Here are a few things to know as you get started:

  • Supported OS: Linux (ARM64 and x86_64) at launch.
  • Session persistence: Sessions persist for up to 14 days.
  • Runtimes: Python 3.11-14 with native code support. Container images also supported.
  • GPU: Support for GPU-accelerated instance types.
  • Integration: Uses the same AgentCore APIs, identity, observability, and policy controls as AgentCore Runtime.
  • Pricing: Standard EC2 pricing plus a management fee for AgentCore orchestration.
  • Regions: US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Mumbai, Singapore, Sydney, Tokyo), and Europe (Frankfurt, Ireland)

To get started, visit the runtime instance in Amazon Bedrock AgentCore documentation and create your first capacity provider.

— seb

Amazon EC2 C9g and C9gd instances powered by AWS Graviton5 processors are now available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-ec2-c9g-and-c9gd-instances-powered-by-aws-graviton5-processors-are-now-available/

When you run compute-intensive workloads like real-time analytics, batch processing, video encoding, scientific modeling, or CPU-based machine learning inference, every percentage point of performance matters. You need instances that deliver higher throughput per vCPU, faster memory access, and more network bandwidth, all while keeping your costs in check.

Today I am happy to announce the general availability of Amazon Elastic Compute Cloud (Amazon EC2) C9g and C9gd instances, powered by AWS Graviton5 processors. C9g instances are compute-optimized and deliver up to 25% higher performance per vCPU compared to previous-generation C8g instances. They feature the fastest memory of any processor instance in the cloud, with DDR5 8800MT/s DIMMs, 5x more L3 cache, and up to 3x higher packet-processing performance compared to Graviton4-based instances. The faster memory and larger caches mean your workloads spend less time waiting on data, translating into higher throughput for in-memory analytics, faster agentic loops, and more responsive real-time applications.

C9g instances are ideal for batch jobs, video encoding pipelines, or distributed analytics that can utilize Amazon Elastic Block Store (Amazon EBS) for storage. It is also a natural fit for agentic AI workloads, where concurrent environments and CPU-bound reasoning steps benefit from Graviton5’s higher core count and larger caches. As AI shifts from answering questions to taking actions, running code, and orchestrating multi-step tasks, the demand for CPU compute is growing, and C9g instances are built for this shift.

Some workloads also need fast local storage alongside that compute power. Choose C9gd when your application benefits from high-speed, low-latency local NVMe SSD storage, for example scratch space during HPC simulations, temporary caches for ML inference, or local buffers for ad-serving engines.

Graviton5-based instances with NVMe instance store volumes also support detailed performance statistics, providing high-resolution I/O metrics, including latency histograms broken down by I/O size, up to 1-second granularity and accessible via Amazon CloudWatch or nvme-cli at no additional cost.

C9g and C9gd instances at a glance
C9g and C9gd instances are available in 11 sizes ranging from medium to 48xlarge, plus a bare metal option. They offer up to 15% higher network bandwidth and 20% higher EBS bandwidth on average across sizes compared to the previous generation, with the largest 48xlarge size delivering up to 100 Gbps of network bandwidth and up to 72 Gbps of EBS bandwidth, a 2x increase.

C9g vCPUs Memory
(GiB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 Up to 15 Up to 12
large 2 4 Up to 15 Up to 12
xlarge 4 8 Up to 15 Up to 12
2xlarge 8 16 Up to 17 Up to 12
4xlarge 16 32 Up to 17 Up to 12
8xlarge 32 64 17 12
12xlarge 48 96 25 18
16xlarge 64 128 34 24
24xlarge 96 192 50 36
48xlarge 192 384 100 72
metal-48xl 192 384 100 72

C9gd instances add local NVMe SSD storage with up to 30% higher storage performance compared to previous-generation local storage instances.

C9gd vCPUs Memory
(GiB)
Instance Storage
(GB)
Network Bandwidth
(Gbps)
EBS Bandwidth
(Gbps)
medium 1 2 1 x 59 Up to 15 Up to 12
large 2 4 1 x 118 Up to 15 Up to 12
xlarge 4 8 1 x 237 Up to 15 Up to 12
2xlarge 8 16 1 x 474 Up to 17 Up to 12
4xlarge 16 32 1 x 950 Up to 17 Up to 12
8xlarge 32 64 1 x 1900 17 12
12xlarge 48 96 3 x 950 25 18
16xlarge 64 128 1 x 3800 34 24
24xlarge 96 192 3 x 1900 50 36
48xlarge 192 384 3 x 3800 100 72
metal-48xl 192 384 3 x 3800 100 72

Both families are well-suited for high-performance computing (HPC), batch processing, gaming, video encoding, scientific modeling, distributed analytics, CPU-based machine learning inference, and ad serving.

Here are some additional capabilities:

  • Instance Bandwidth Configuration (IBC) lets you adjust the allocation of bandwidth between Amazon EBS and Amazon VPC networking by up to 25%, helping you optimize performance for workloads with specific bandwidth requirements such as databases and caching.
  • ENA Express support for enhanced networking.
  • Up to 128 EBS volumes can be attached to virtual instances.
  • Support for Savings Plans, On-Demand, Spot Instances, Dedicated Instances, and Dedicated Hosts.

Nitro Isolation Engine
C9g and C9gd instances are the first compute optimized Amazon EC2 instances to feature the AWS Nitro Isolation Engine, a new capability of the AWS Nitro System. The Nitro Isolation Engine is a purpose-built component of the Nitro Hypervisor, implemented in Rust, that enforces isolation between virtual machines. It mediates all access to VM memory, CPU register state, and I/O devices through a minimal set of APIs.

To learn more about the Nitro Isolation Engine, visit the blog post. For details on the formal verification results, including scope and assumptions, see our technical white paper.

Now available
Amazon EC2 C9g and C9gd instances are now available in US East (Ohio, N. Virginia), US West (Oregon), and Europe (Frankfurt). Additional regions will follow.

You can launch C9g and C9gd instances today using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs. For pricing information, visit the Amazon EC2 Pricing page.

To learn more, visit the Amazon EC2 C9g and C9gd instances page and send feedback to AWS re:Post for EC2 or through your usual AWS Support contacts.

— seb

Automate public TLS certificate issuance with ACME support in AWS Certificate Manager

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/automate-public-tls-certificate-issuance-with-acme-support-in-aws-certificate-manager/

If you manage TLS certificates for your applications, you know the challenge: certificates expire, and when they do, your customers see errors or your service goes down. As certificate validity periods get shorter (the Certification Authority (CA)/Browser Forum mandates reduced maximum validity to 100 days starting March 2027, and to 47 days by 2029), manual renewal processes become untenable. You need automation.

Automatic Certificate Management Environment (ACME) is an open protocol for requesting, renewing, and revoking TLS certificates without human intervention. It’s the same protocol behind Let’s Encrypt, and it’s supported by dozens of clients across every platform.

Today we’re announcing ACME support for public certificates in AWS Certificate Manager (ACM). ACM now provides a fully managed ACME server endpoint that works with any ACMEv2-compatible client, such as Certbot, cert-manager for Kubernetes, acme.sh, or any other client you already use. You can issue public TLS certificates from Amazon Trust Services through the standard ACME protocol.

Before today, if you wanted automated certificate management using the ACME protocol, you relied on external certificate authorities alongside ACM, leading to a fragmented visibility experience. Some certificates lived in ACM, others were managed externally with no central dashboard. PKI administrators had limited ability to control who could request certificates or which domains were allowed.

With ACME support in ACM, you can now set up one or more managed ACME endpoint that allows you to centrally manage and monitor ACME certificate usage across your organization.

As a PKI administrator, you get centralized controls that go beyond basic certificate issuance. You can bind IAM roles to ACME accounts for fine-grained access control over which domains each client can request. You can define domain scopes at the endpoint level to enforce organization-wide policies. And you get centralized monitoring and visibility in the same place: AWS CloudTrail logs every certificate request for auditability, Amazon CloudWatch tracks operational metrics, and ACM sends expiry notifications when certificates are approaching renewal. Using ACM, your PKI team can search all certificates, whether issued through the ACM console, an API call, or ACME.

How it works
To get started, you first set up a dedicated ACME endpoint, configure authorization controls using External Account Binding (EAB), validate which domains the endpoint can issue certificates for, and point your existing ACME clients to the new endpoint.

The domain validation step is important: it separates who can set up certificate issuance from who can request certificates. The PKI administrator validates domains once at the endpoint level, using DNS credentials that stay with the admin. Application owners who need certificates never touch DNS. They register with an EAB credential, and the endpoint enforces which domains and scopes they’re allowed to request. This means you can distribute certificate automation broadly across your organization without distributing DNS keys along with it.

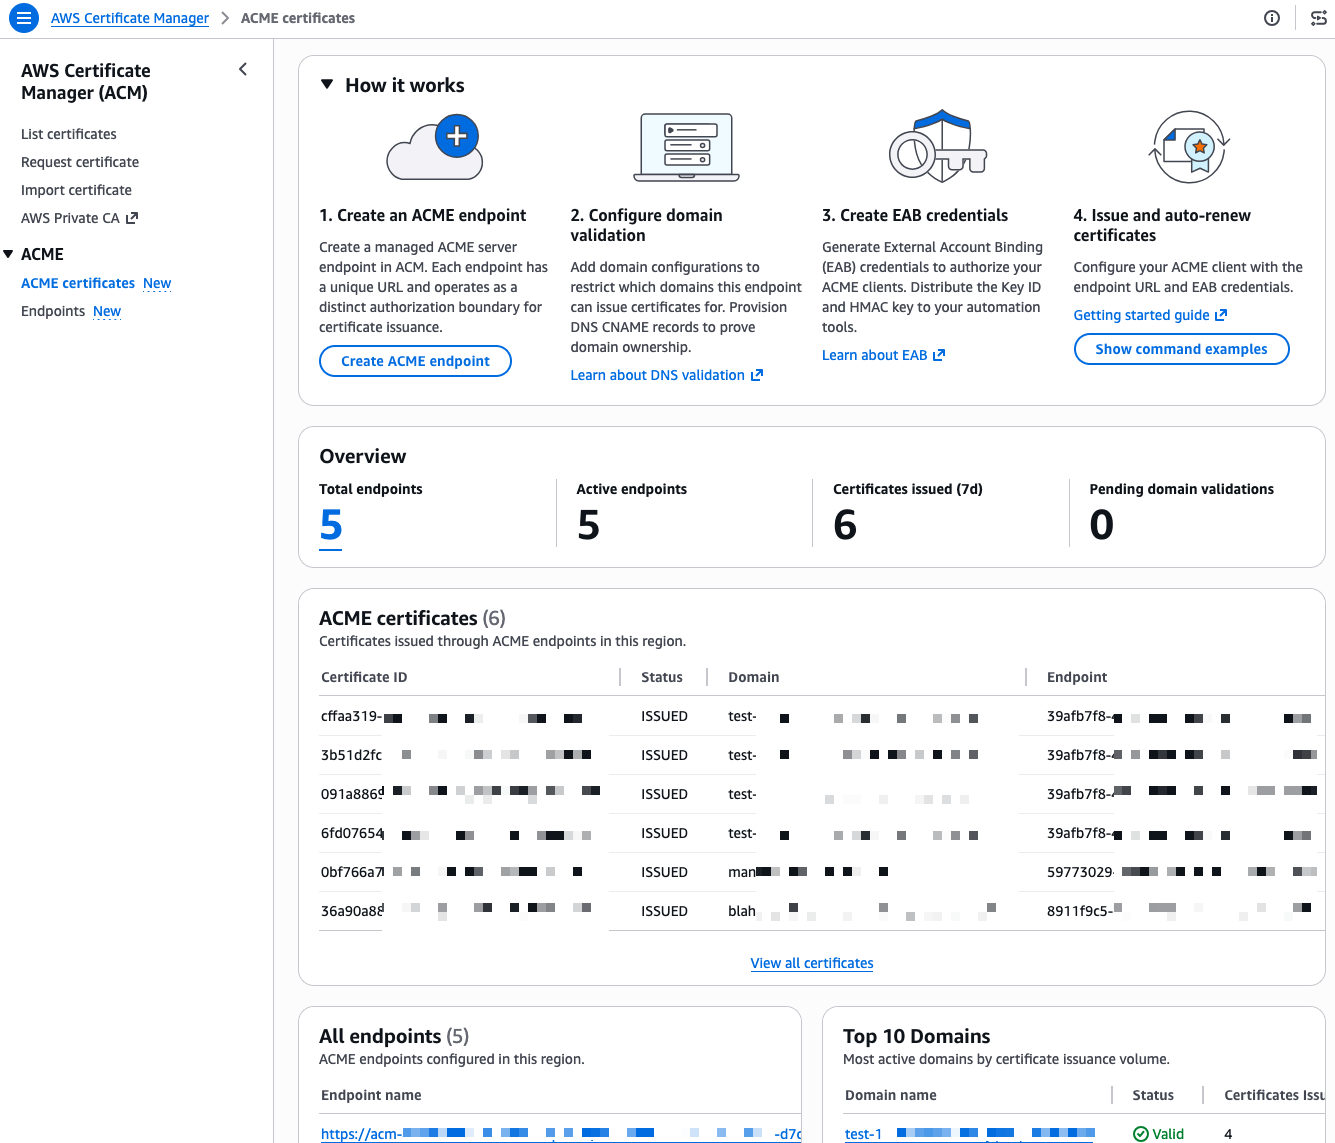
I start this demo from the ACME certificates page in the AWS Certificate Manager console.

ACME Console

I already have a few endpoints and certificates in this account, I walk you through creating a new one from scratch. First, I select Create ACME endpoint.

ACME - Ceeate endpoint 1

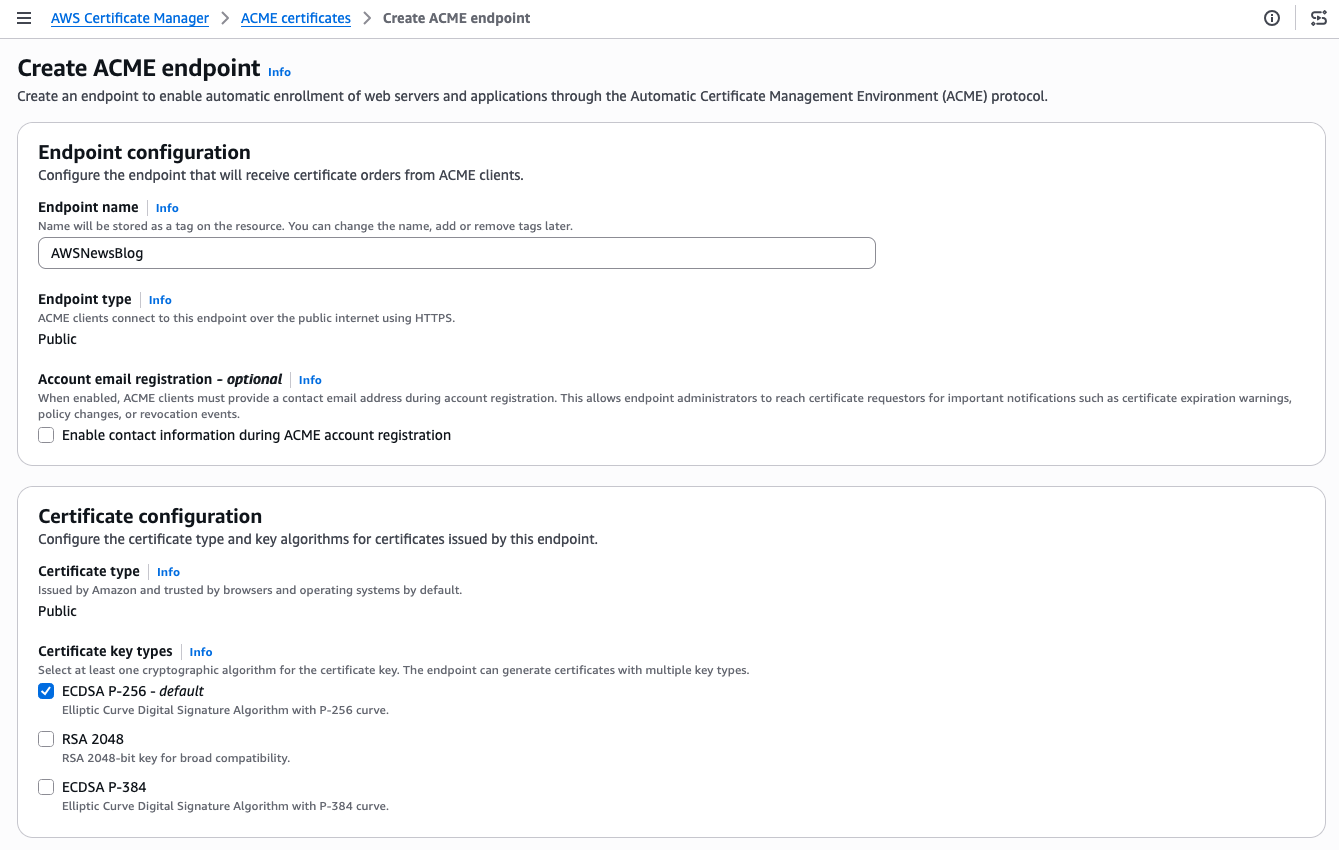
I give my endpoint a name. The Endpoint type is Public. ACME clients will connect over the public internet. The Certificate type is Public. The certificate will be issued by Amazon Trust Services and trusted by browsers and operating systems by default. For the certificate key type, I keep the default ECDSA P-256. RSA 2048 and ECDSA P-384 are also available if your clients require them.

ACME - Ceeate endpoint 2

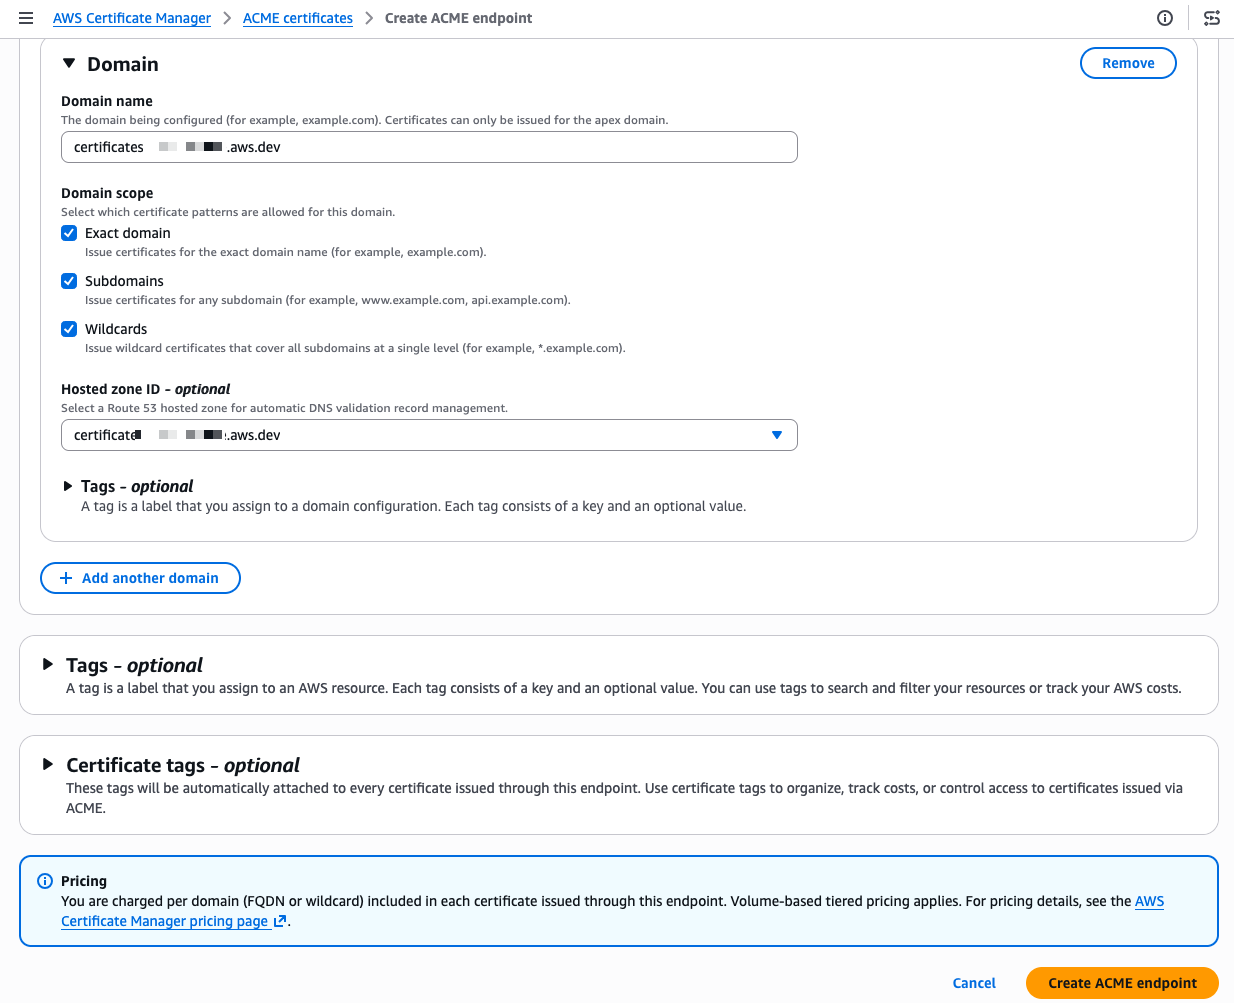
Scrolling down, I configure the domain. I enter my domain name and select the domain scope. The scope controls exactly what certificate patterns your ACME clients are allowed to request for this domain. If I check only Exact domain, clients can only request certificates for that specific domain name. Adding Subdomains allows certificates for any subdomain (for example, api.example.com or dev.example.com). Adding Wildcards allows wildcard certificates (*.example.com). By leaving a scope unchecked, you prevent any client using this endpoint from requesting that type of certificate, even if their ACME request is otherwise valid. For a production endpoint, you might enable only Exact domain and Subdomains while leaving Wildcards unchecked to enforce a stricter security posture.

I also select my Amazon Route 53 hosted zone from the drop down menu. ACM then automatically creates the DNS CNAME records needed for domain validation, so I don’t have to do it manually. When my domain is hosted outside of Route 53, I manually create the provided CNAME record at my DNS provider instead. This is a meaningful difference from typical ACME setups where each client handles its own domain verification independently.

These centralized controls give PKI administrators a single place to authenticate domains, restrict which certificate types (ECDSA or RSA) clients can request, and further limit wildcard issuance. Having these governance capabilities built in means you don’t need to purchase a separate certificate lifecycle management product or invest in building a custom policy layer yourself, both of which come at significant cost and operational overhead.

I select Create ACME endpoint

ACME - DNS configuration

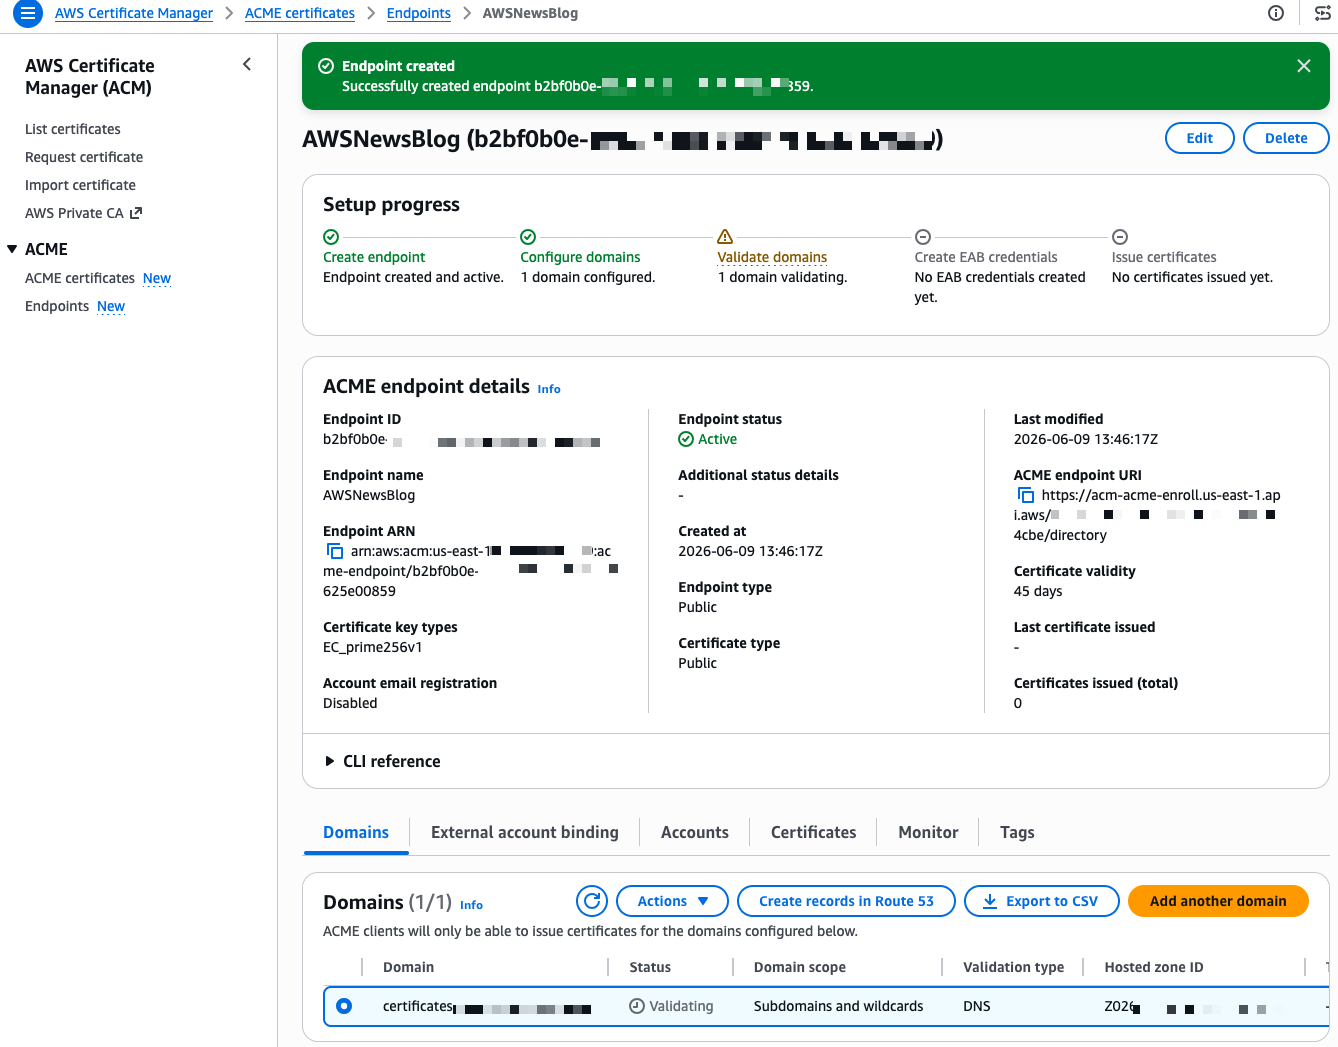
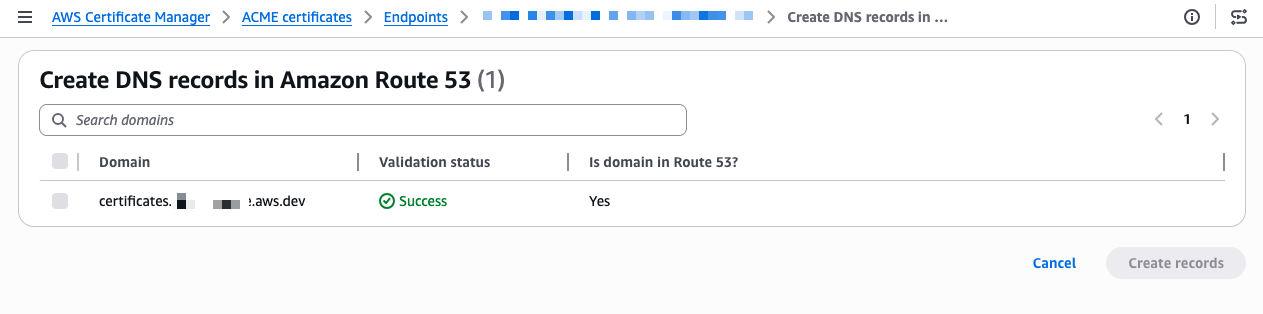
After a few seconds, the endpoint is created. The console shows a Setup progress tracker with the next steps. My domain shows a “Validating” status. The validation method is DNS validation, where ACM verifies that you control the domain by checking for a specific CNAME record. Because I selected my Route 53 hosted zone during creation, I select Create records in Route 53 to let ACM handle the DNS validation automatically.

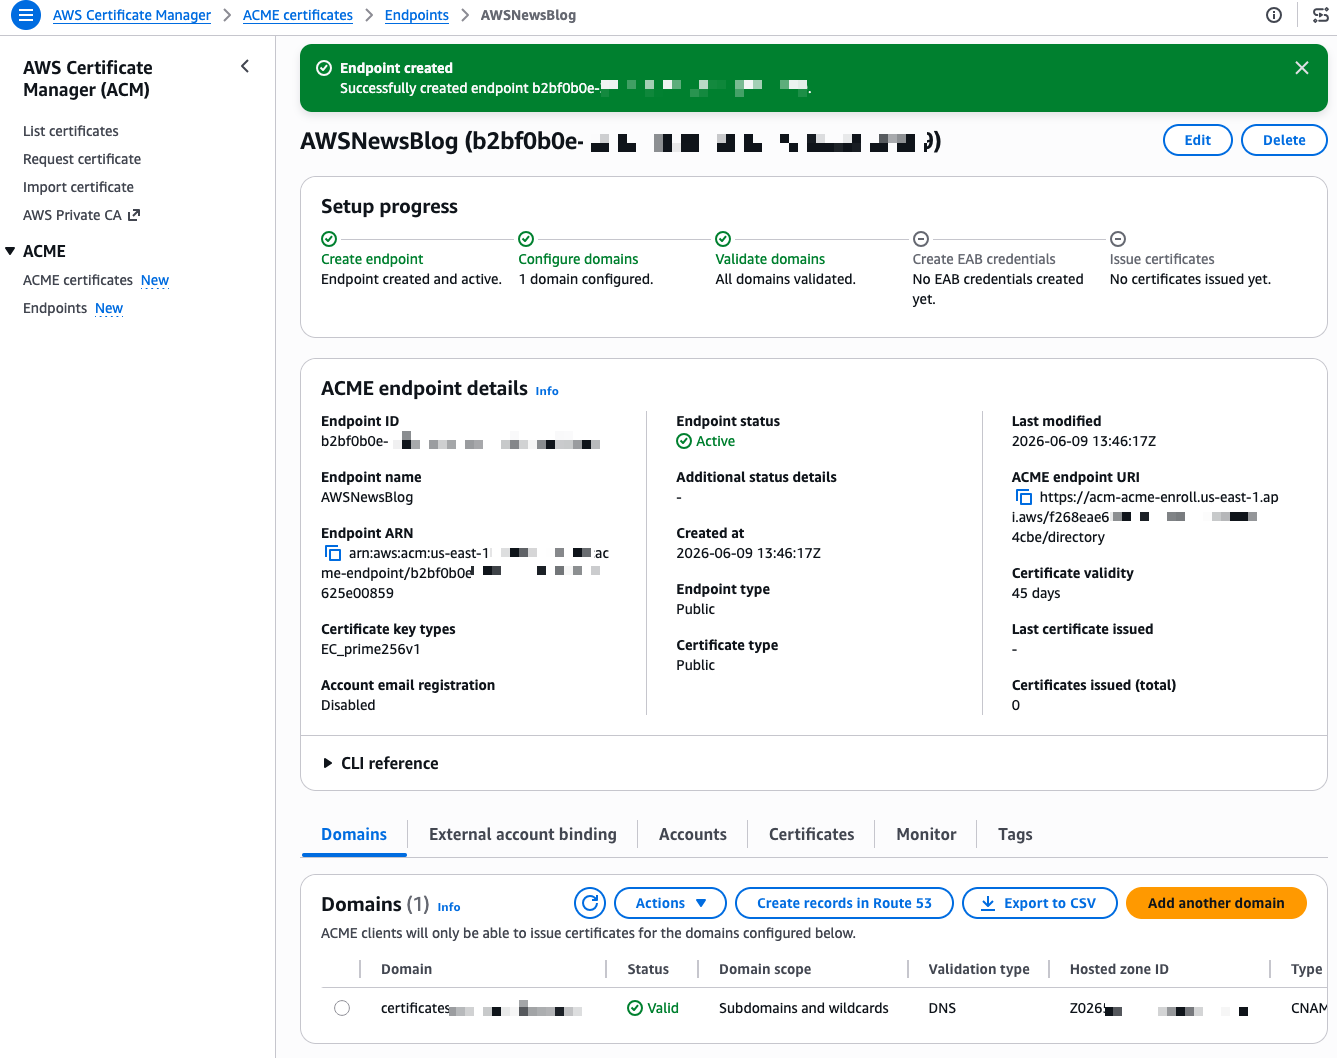
ACME - DNS successThe validation completes in a few seconds and the status changes to Success.

ACME - External Account Binding 1

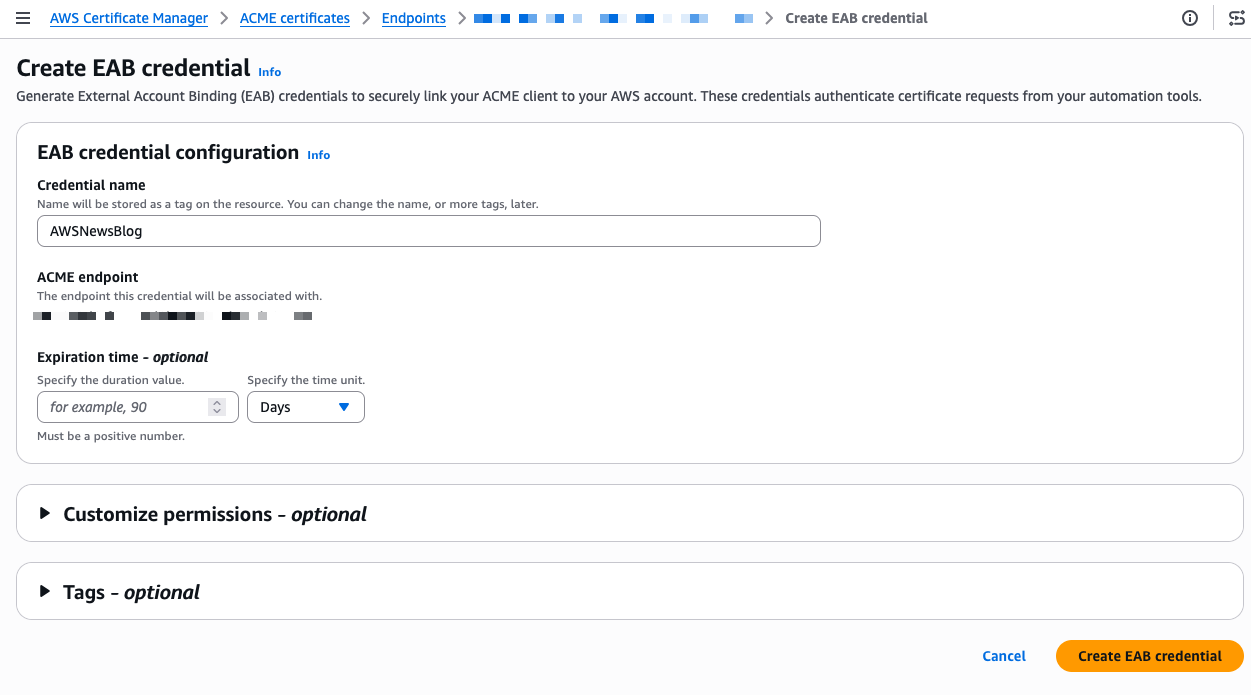
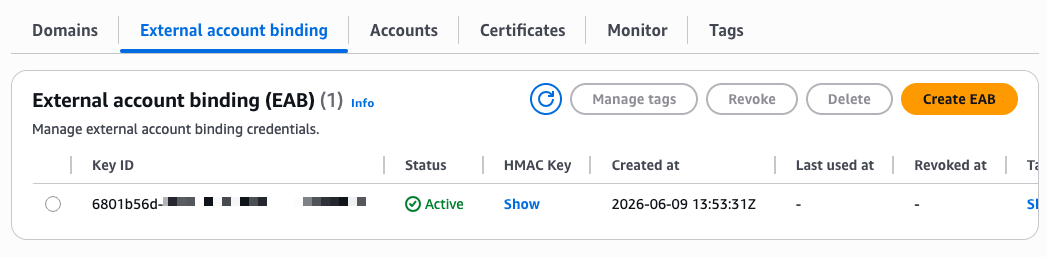
Now I need to create External Account Binding (EAB) credentials. EAB credentials are a key identifier and HMAC key pair that lets your ACME client register an account with the ACME server. Once registered, the client generates its own asymmetric key pair, which is then used to authenticate all subsequent certificate requests. On the endpoint details page, I select the External account binding tab, then select Create EAB. I give the credential a name and optionally set an expiration time, ideally no longer than needed to complete client registration.

ACME - External Account Binding 2

ACME - end of configuration - show key

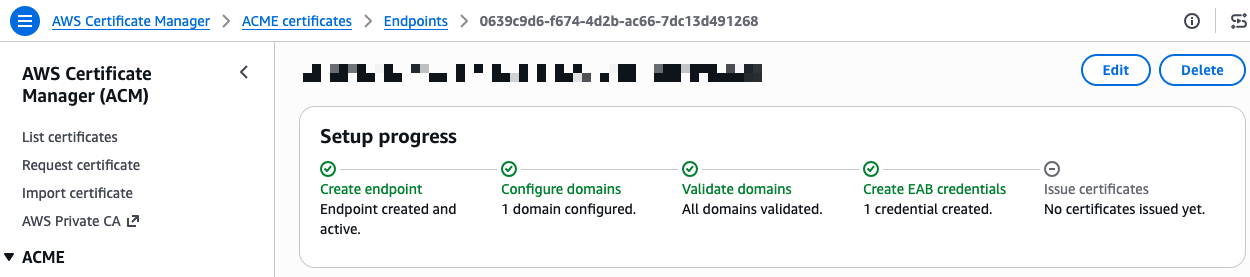
After I select Create EAB credential, the console shows the Key ID and HMAC Key. I note these values because I need them to configure my ACME client. The setup progress now shows four green checkmarks.

ACME - end of configuration - success

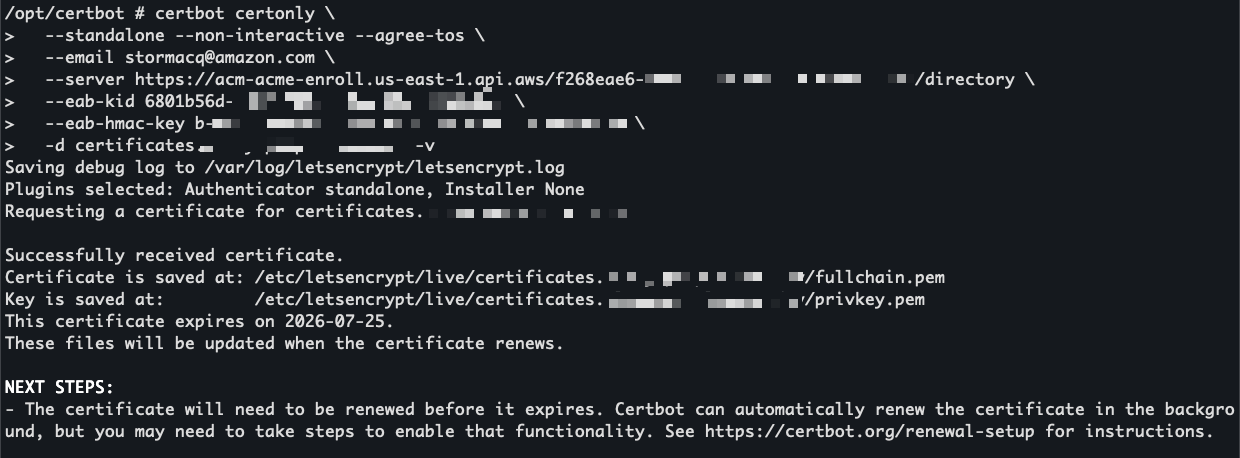
I’m ready to request a certificate. On the endpoint details page, I expand the CLI reference section. The console provides ready-to-use command examples for both Certbot and acme.sh. I copy the Certbot command and run it inside a container using the certbot/certbot image.

certbot certonly --standalone --non-interactive --agree-tos \
    --email <EMAIL> \
    --server https://acm-acme-enroll.us-east-1.api.aws/<ENDPOINT_ID>/directory \
    --eab-kid <EAB_KID> \
    --eab-hmac-key <EAB_HMAC_KEY> \
    --issuance-timeout <ISSUANCE_TIMEOUT> \
    -d <DOMAIN>

I replace the placeholders with my endpoint URL, EAB credentials, and domain name. The --eab-kid and --eab-hmac-key arguments are how Certbot registers with your ACME endpoint using the External Account Binding credentials I generated earlier. Each ACME client has its own syntax for this step, so check your client’s documentation for the exact flags.

Certbot contacts the ACME endpoint and returns a valid certificate signed by Amazon Trust Services.

Certbot to obtain a certificate through ACME

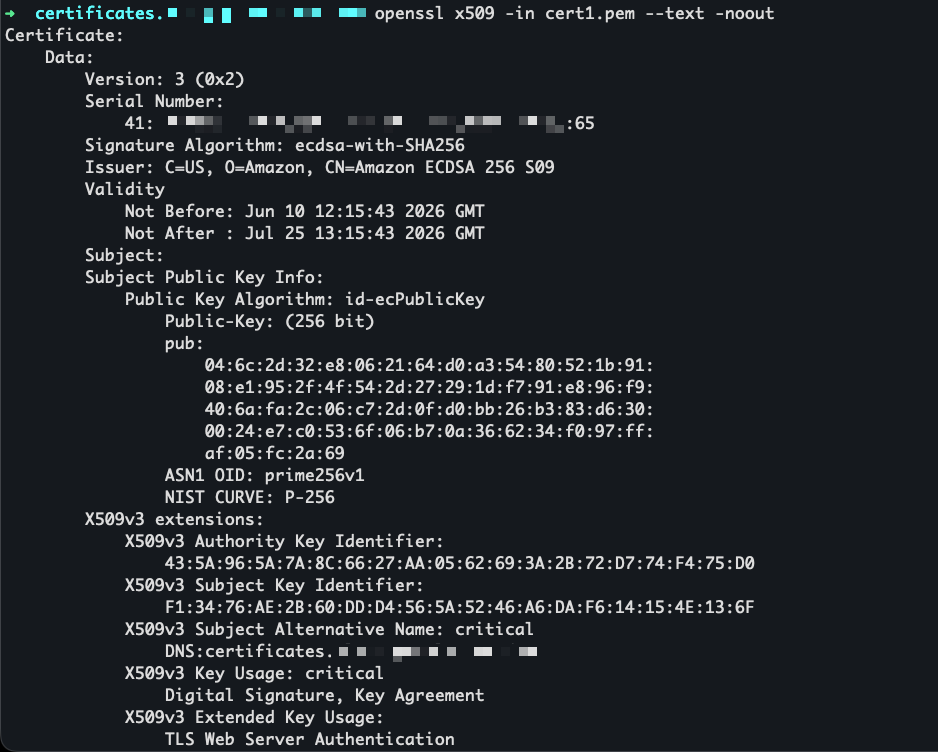
I use openssl to view the certificate before installing it.

openssl to view the certificate

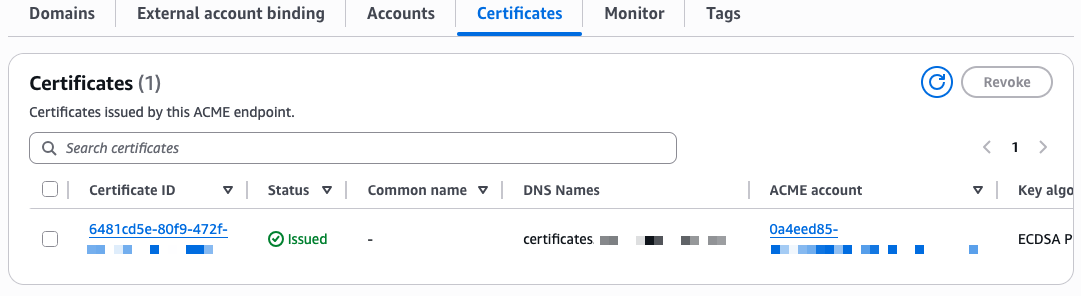
The certificate is now visible in the ACM console under the ACME certificates tab, alongside any certificates issued through the console or API.

Certoficate view in the ACME console

Availability and pricing
ACME support in AWS Certificate Manager is available today in all commercial AWS Regions and will be available in AWS GovCloud (US), the China Regions, and the AWS European Sovereign Cloud partitions at a later date.

Pricing is per domain included in each certificate at the time of issuance, with a different price for fully qualified domain names and wildcards. Volume tiers are calculated based on total domain occurrences across all certificates issued per month in your AWS account. For details, see the ACM pricing page.

To get started, visit the ACM section on the AWS console or read the documentation.

— seb

AWS Weekly Roundup: BYOM for Amazon RDS for SQL Server, AWS IoT Device SDK for Swift, and more (June 8, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-byom-for-amazon-rds-for-sql-server-aws-iot-device-sdk-for-swift-and-more-june-8-2026/

This week, the AWS IoT Device SDK for Swift reached general availability. As a member of the Swift Server Workgroup (SSWG), this one caught my attention. The SDK brings production-ready MQTT 5 connectivity, Device Shadow, Jobs, and fleet provisioning to Swift developers on macOS, iOS, tvOS, and Linux.

Swift on IoT and Edge devices, an AI generated illustration

I’m curious to see what you will build with it. Swift on the server has matured over the past few years, and now it reaches IoT devices too. This connects to a broader trend of running Swift at the edge. WendyOS, for example, is an open-source operating system for physical AI that offers first-class Swift support for deploying apps to NVIDIA Jetson and Raspberry Pi hardware. Between server-side Swift, IoT, and edge computing, the language is showing up in places that would have surprised most people a few years ago.

Now, let’s get into this week’s AWS news.

Headlines
Amazon RDS for SQL Server supports Bring Your Own Media — Customers who migrate SQL Server applications from on-premises environments can now reuse their existing Microsoft SQL Server licenses, including Software Assurance, through Microsoft’s License Mobility program on Amazon RDS. BYOM is integrated with AWS License Manager for tracking license usage and compliance. Read more.

Amazon Cognito now supports multi-Region replication — You can now synchronize user and machine identity data, including credentials, user pool configurations, and federation setups, to a secondary user pool in a standby Region in near real-time. In the event of a disruption in the primary Region, signed-in users continue accessing their applications without re-authenticating, and registered users can sign in with their existing credentials. Multi-Region replication is available as an add-on for user pools in Essentials or Plus feature tiers across 16 Regions. Read more.

GPT-5.5, GPT-5.4, and Codex from OpenAI are now generally available on Amazon Bedrock — You can now use GPT-5.5 and GPT-5.4 in production workloads on Amazon Bedrock and build with Codex for AI-powered software development, with the same security, governance, and operational controls you already use across AWS. GPT-5.5 is the most capable model from OpenAI, excelling at agentic coding, data analysis, and multi-step autonomous tasks. Codex is available through the Codex App, the Codex CLI, and IDE integrations with Visual Studio Code, JetBrains, and Xcode. Pricing matches OpenAI first-party rates, and usage counts toward existing AWS commitments. Read more.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Upcoming AWS events
Learn more about AWS, browse and join upcoming AWS-led in-person and virtual events, startup events, and developer-focused events as well as AWS Summits and AWS Community Days. Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

Improve your application resilience with Amazon Cognito multi-Region replication

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/improve-your-application-resilience-with-amazon-cognito-multi-region-replication/

As a developer advocate working with web and mobile application developers, I’ve often heard about the need to maintain consistent user authentication in the unlikely event of a regional service interruption. The increasing use of agentic AI, microservices, automation, and service accounts has sparked a similar need for machine-to-machine authentication. Today, I’m excited to share two important updates to Amazon Cognito: multi-Region replication for improved resilience, and support for customer managed keys for more control encryption control.

Many applications rely on Amazon Cognito to handle user and machine-to-machine authentication, and to manage user profiles. When building for high availability, having consistent data across different AWS Regions is a key approach, and until now, achieving that consistency came with significant challenges. Engineering teams spent significant time building and maintaining custom replication solutions to synchronize configurations across Regions. Manual export and import of user data between Regions created security risks from potential data exposure and introduced opportunities for data inconsistencies. During regional transitions, end users experienced disruptions like forced password resets and re-authentication. For machine-to-machine communications, teams had to create new app clients in the secondary region, which meant reconfiguring their applications and updating OAuth-protected resources to accept access tokens issued by the new regional issuer. These challenges made it difficult to maintain uninterrupted operations across Regions.

With multi-Region replication, Amazon Cognito automatically maintains a synchronized copy of your user data and machine secrets in a secondary AWS Region of your choice. The replication flows in one direction, from your primary Region to the secondary Region. This includes user profiles, credentials, and pool configurations. The secondary Region operates in read-only mode, focusing on maintaining authentication capabilities. Existing sessions continue uninterrupted.

When you need to direct traffic to the secondary Region, your existing users can continue signing in with their existing credentials without disruption, and currently signed-in users remain authenticated because both regions recognize access tokens issued by either region. Multi-Region replication supports all authentication methods, including federated sign-in through social providers (Amazon, Google, Apple, Facebook), Security Assertion Markup Language (SAML) and OpenID Connect (OIDC) integrations, and API authorization flows. This approach maintains availability for both customer-facing applications and machine-to-machine communications in your backend services. While authentication continues without interruption, operations like new user registration or profile updates are not available during failover.

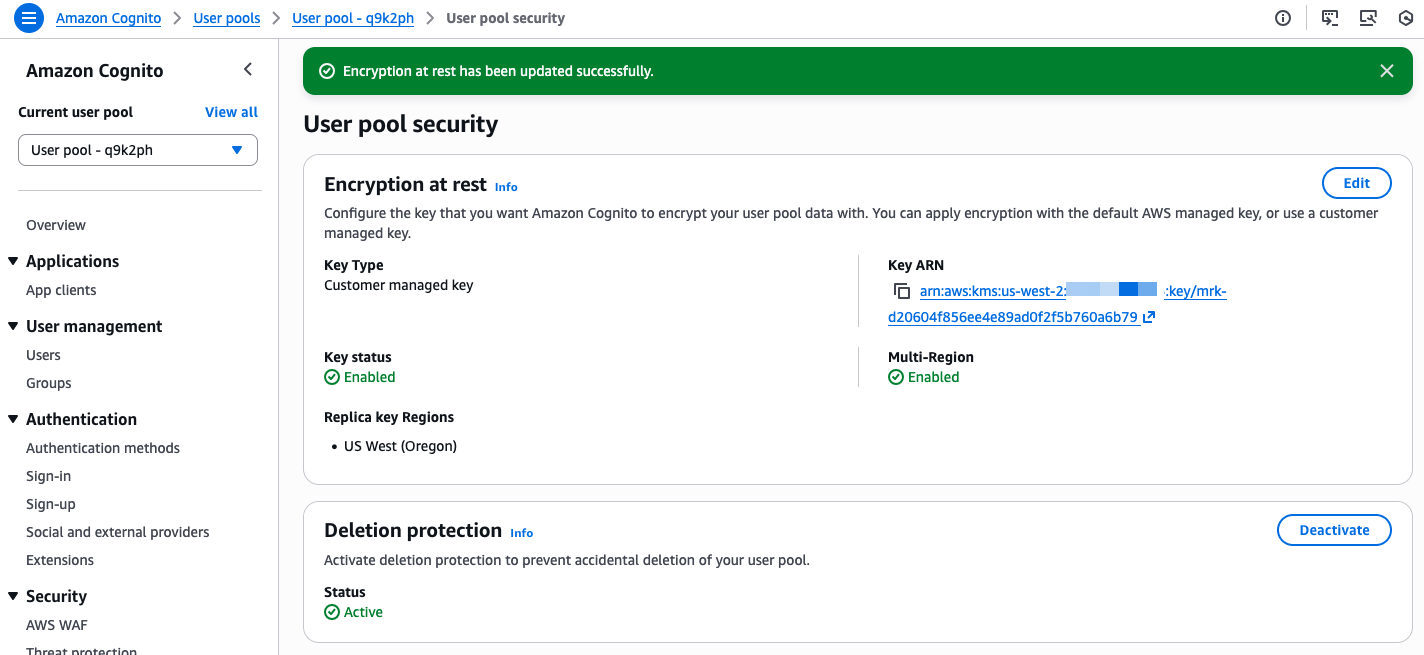
Before configuring multi-Region replication, you must configure a multi-Region customer managed key stored in AWS Key Management Service (AWS KMS) to encrypt your user data at rest. These keys provide consistent encryption across Regions while giving you control over your encryption strategy.

How this works in practice
I start this demo with an existing Cognito user pool in the us-west-2 (Oregon) Region. I want to configure replication to us-east-1 (Northern Virginia). I also have a customer managed key replicated in these two Regions.

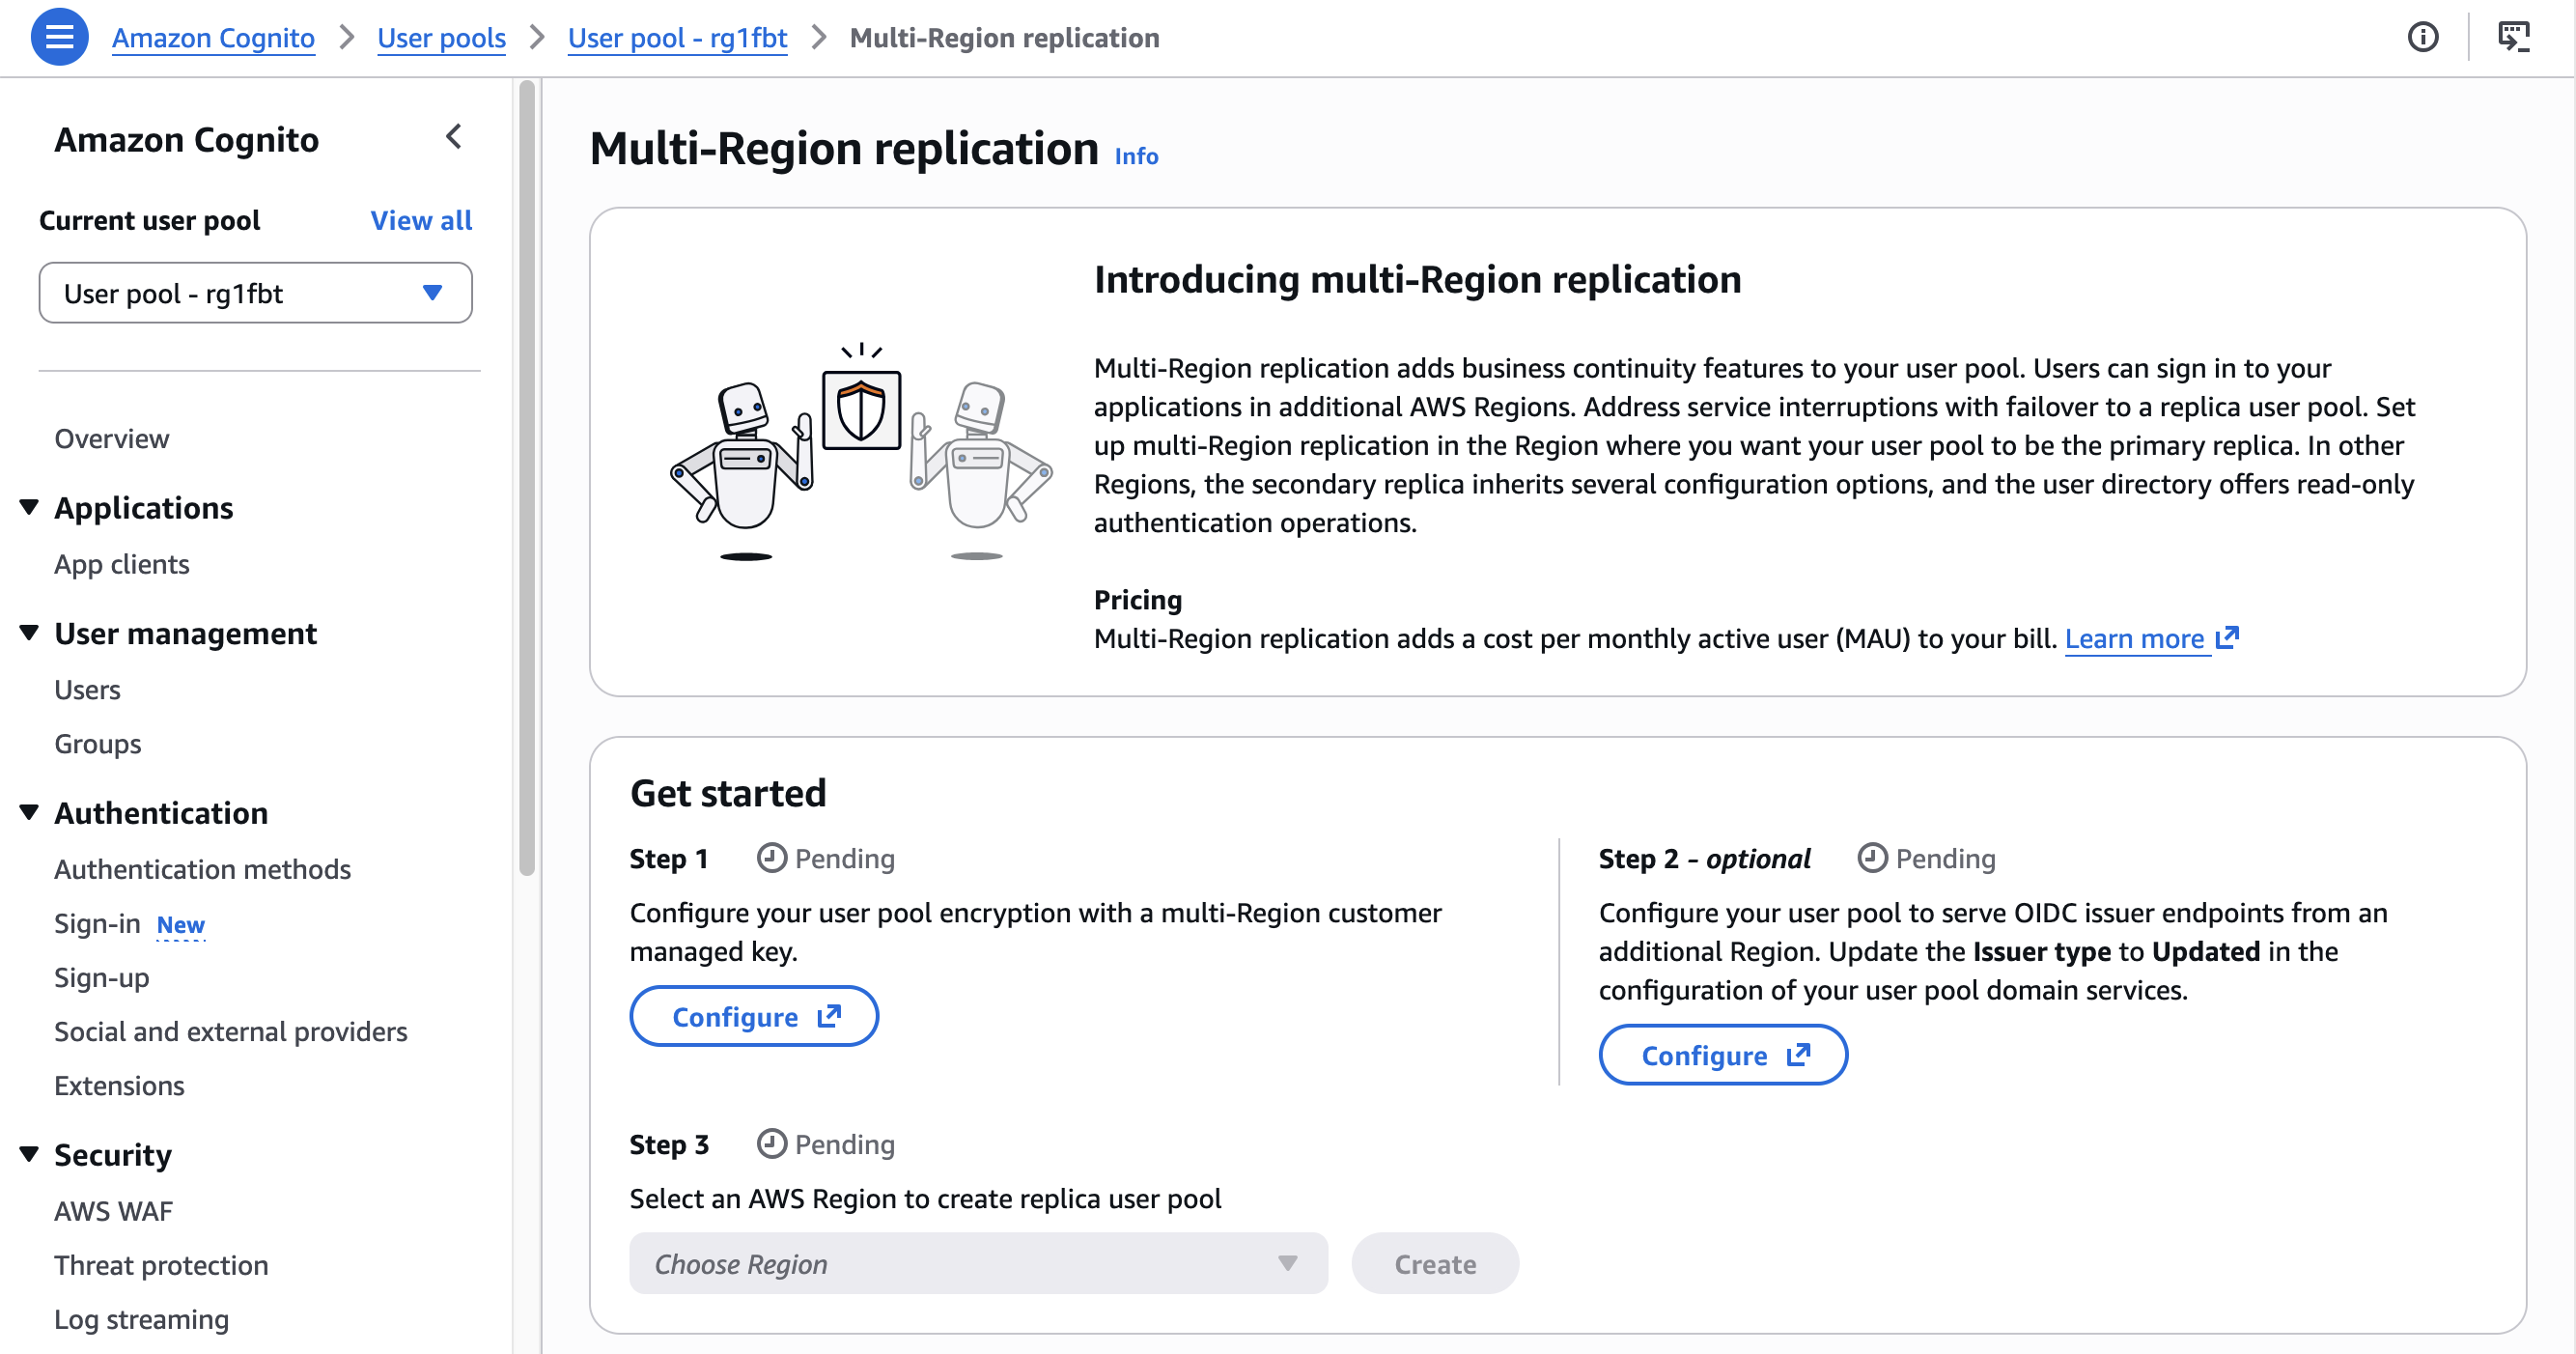
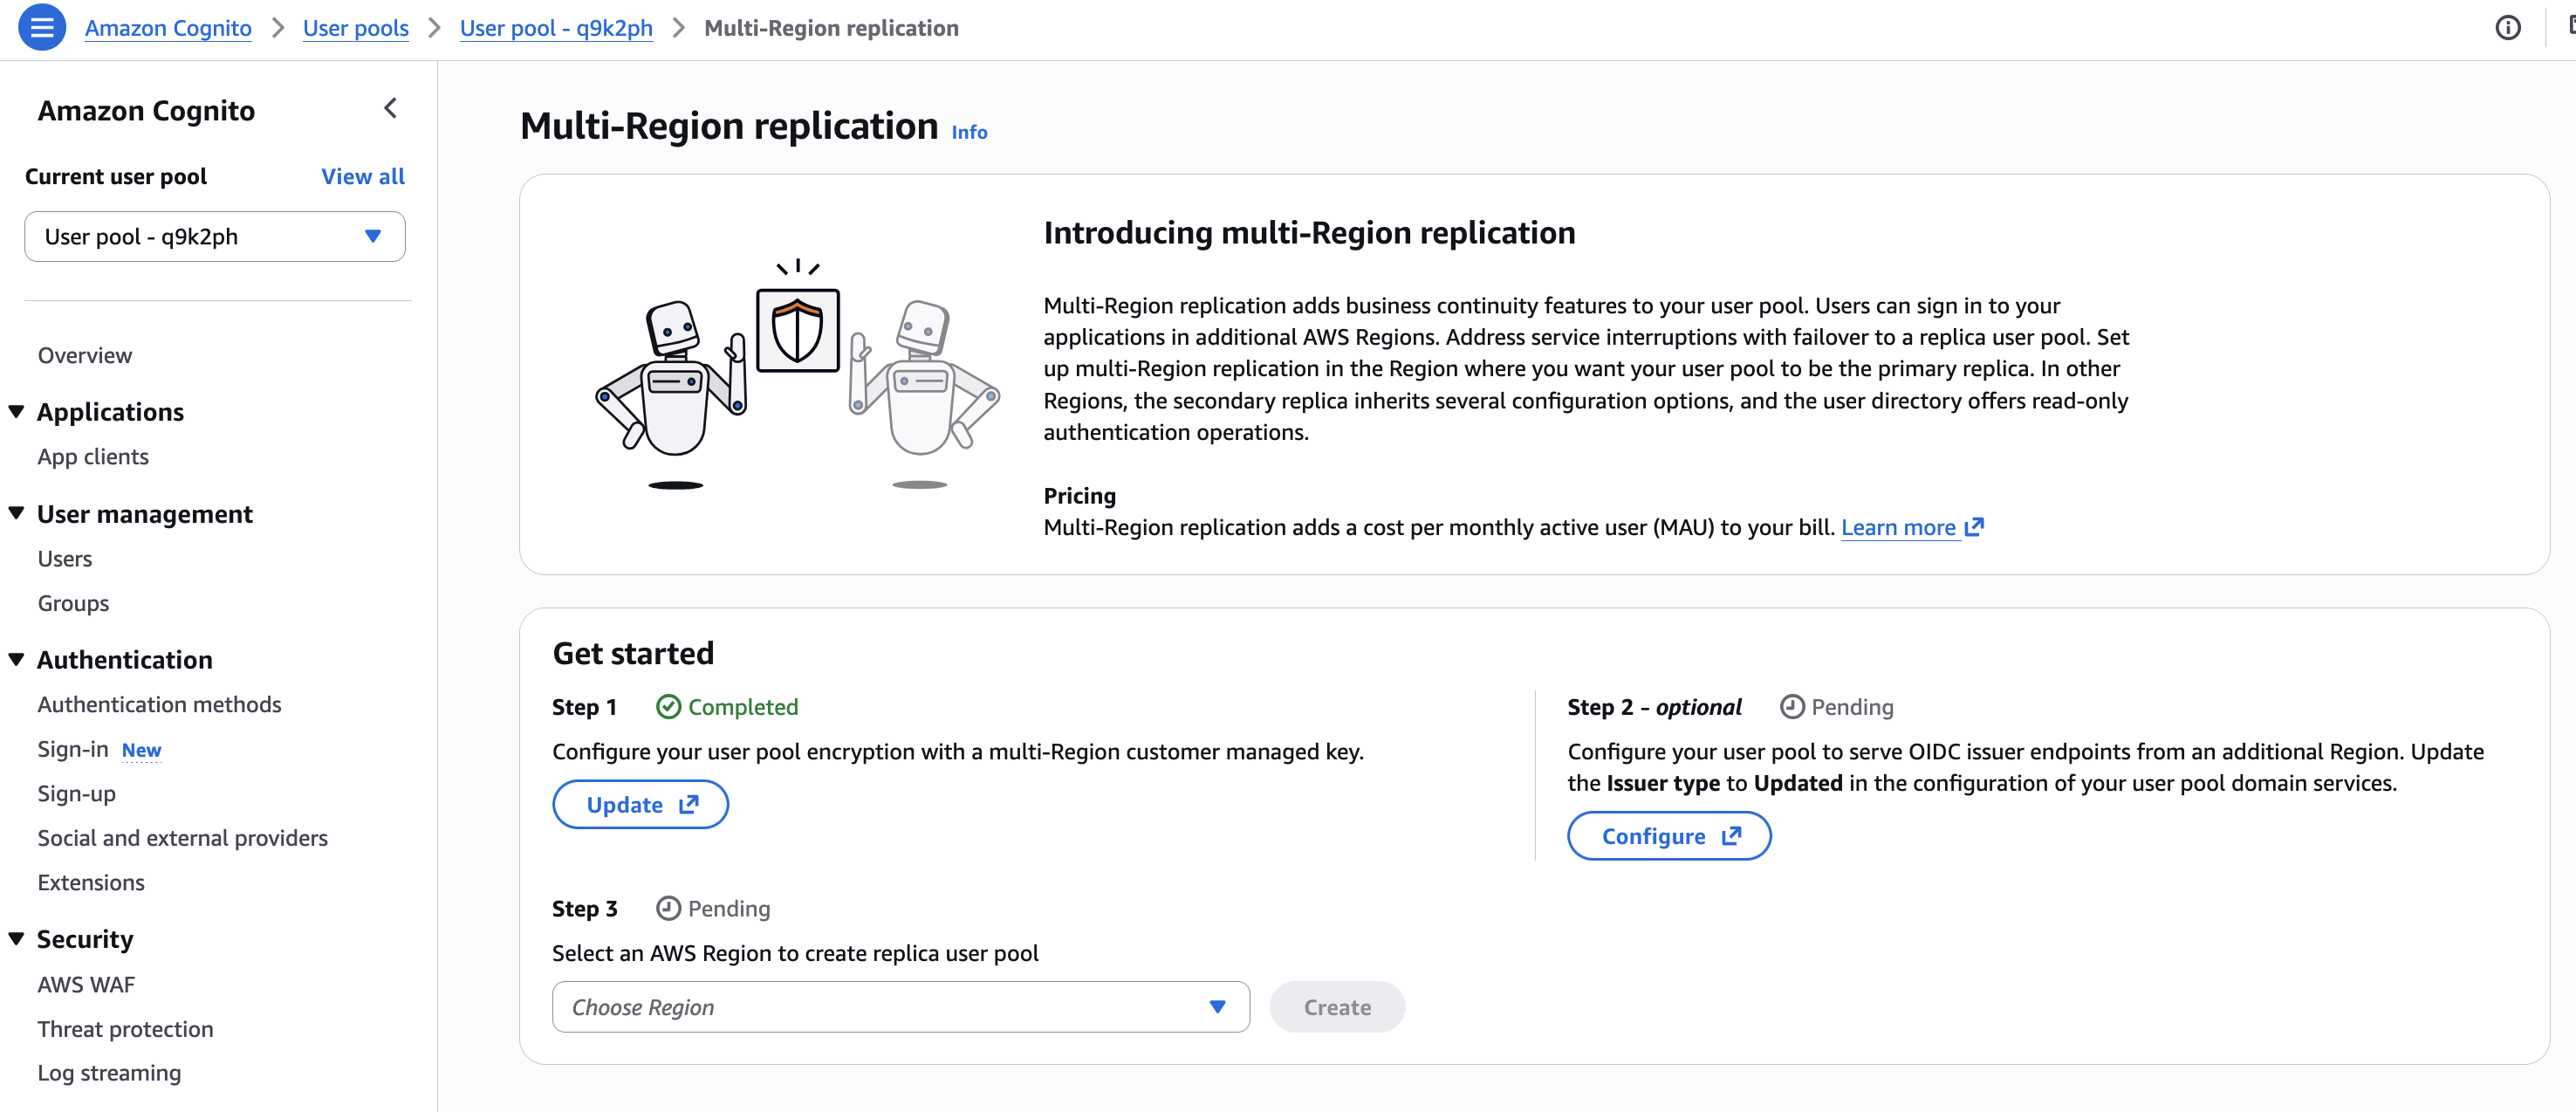
Configuring multi-Region replication is just three steps. The AWS Management Console guides me through the steps: set up a custom key for encryption, configure multi-region OIDC endpoints, and configure the replication itself.

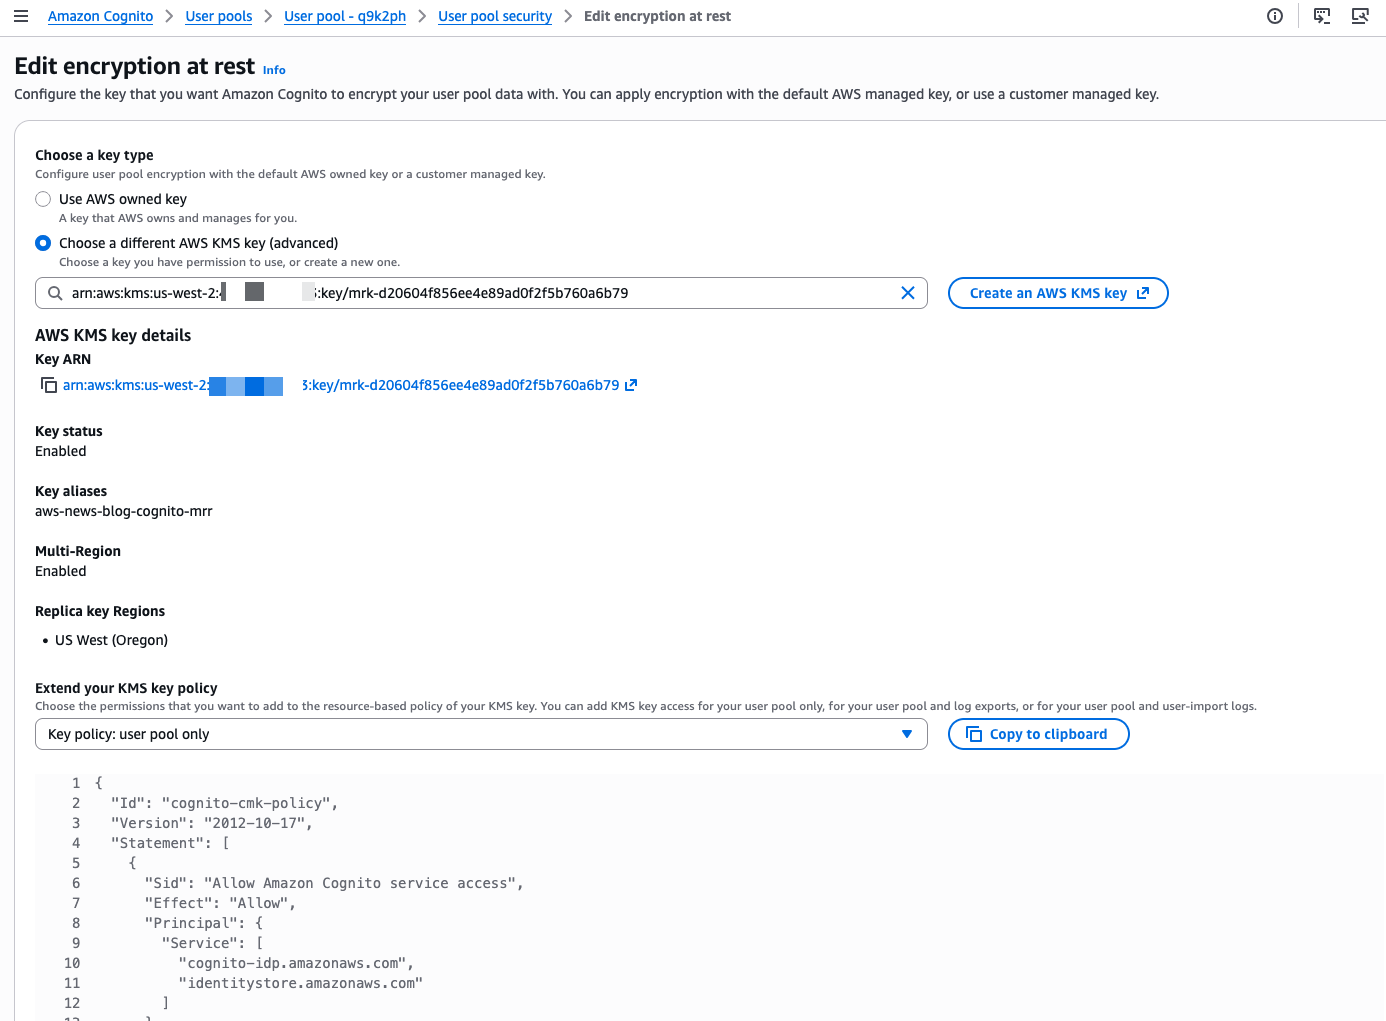
First, I set up a custom AWS KMS key to encrypt the data at rest.

Cognito Multi-Region replication - initial state

I select the custom key I created. I also update the key policy to allow Amazon Cognito to access and use the key. The console shows the correct IAM policy statements to add to my key policy.

Cognito Multi-Region replication - select CMK

The console confirms when the custom key is selected and correctly configured.

Cognito Multi-Region replication - confirm CMK

Second, I follow the console instructions to configure the OIDC issuer type. On Step 2 – optional, I choose Configure.

Cognito Multi-Region replication - configure multi region OIDC 1

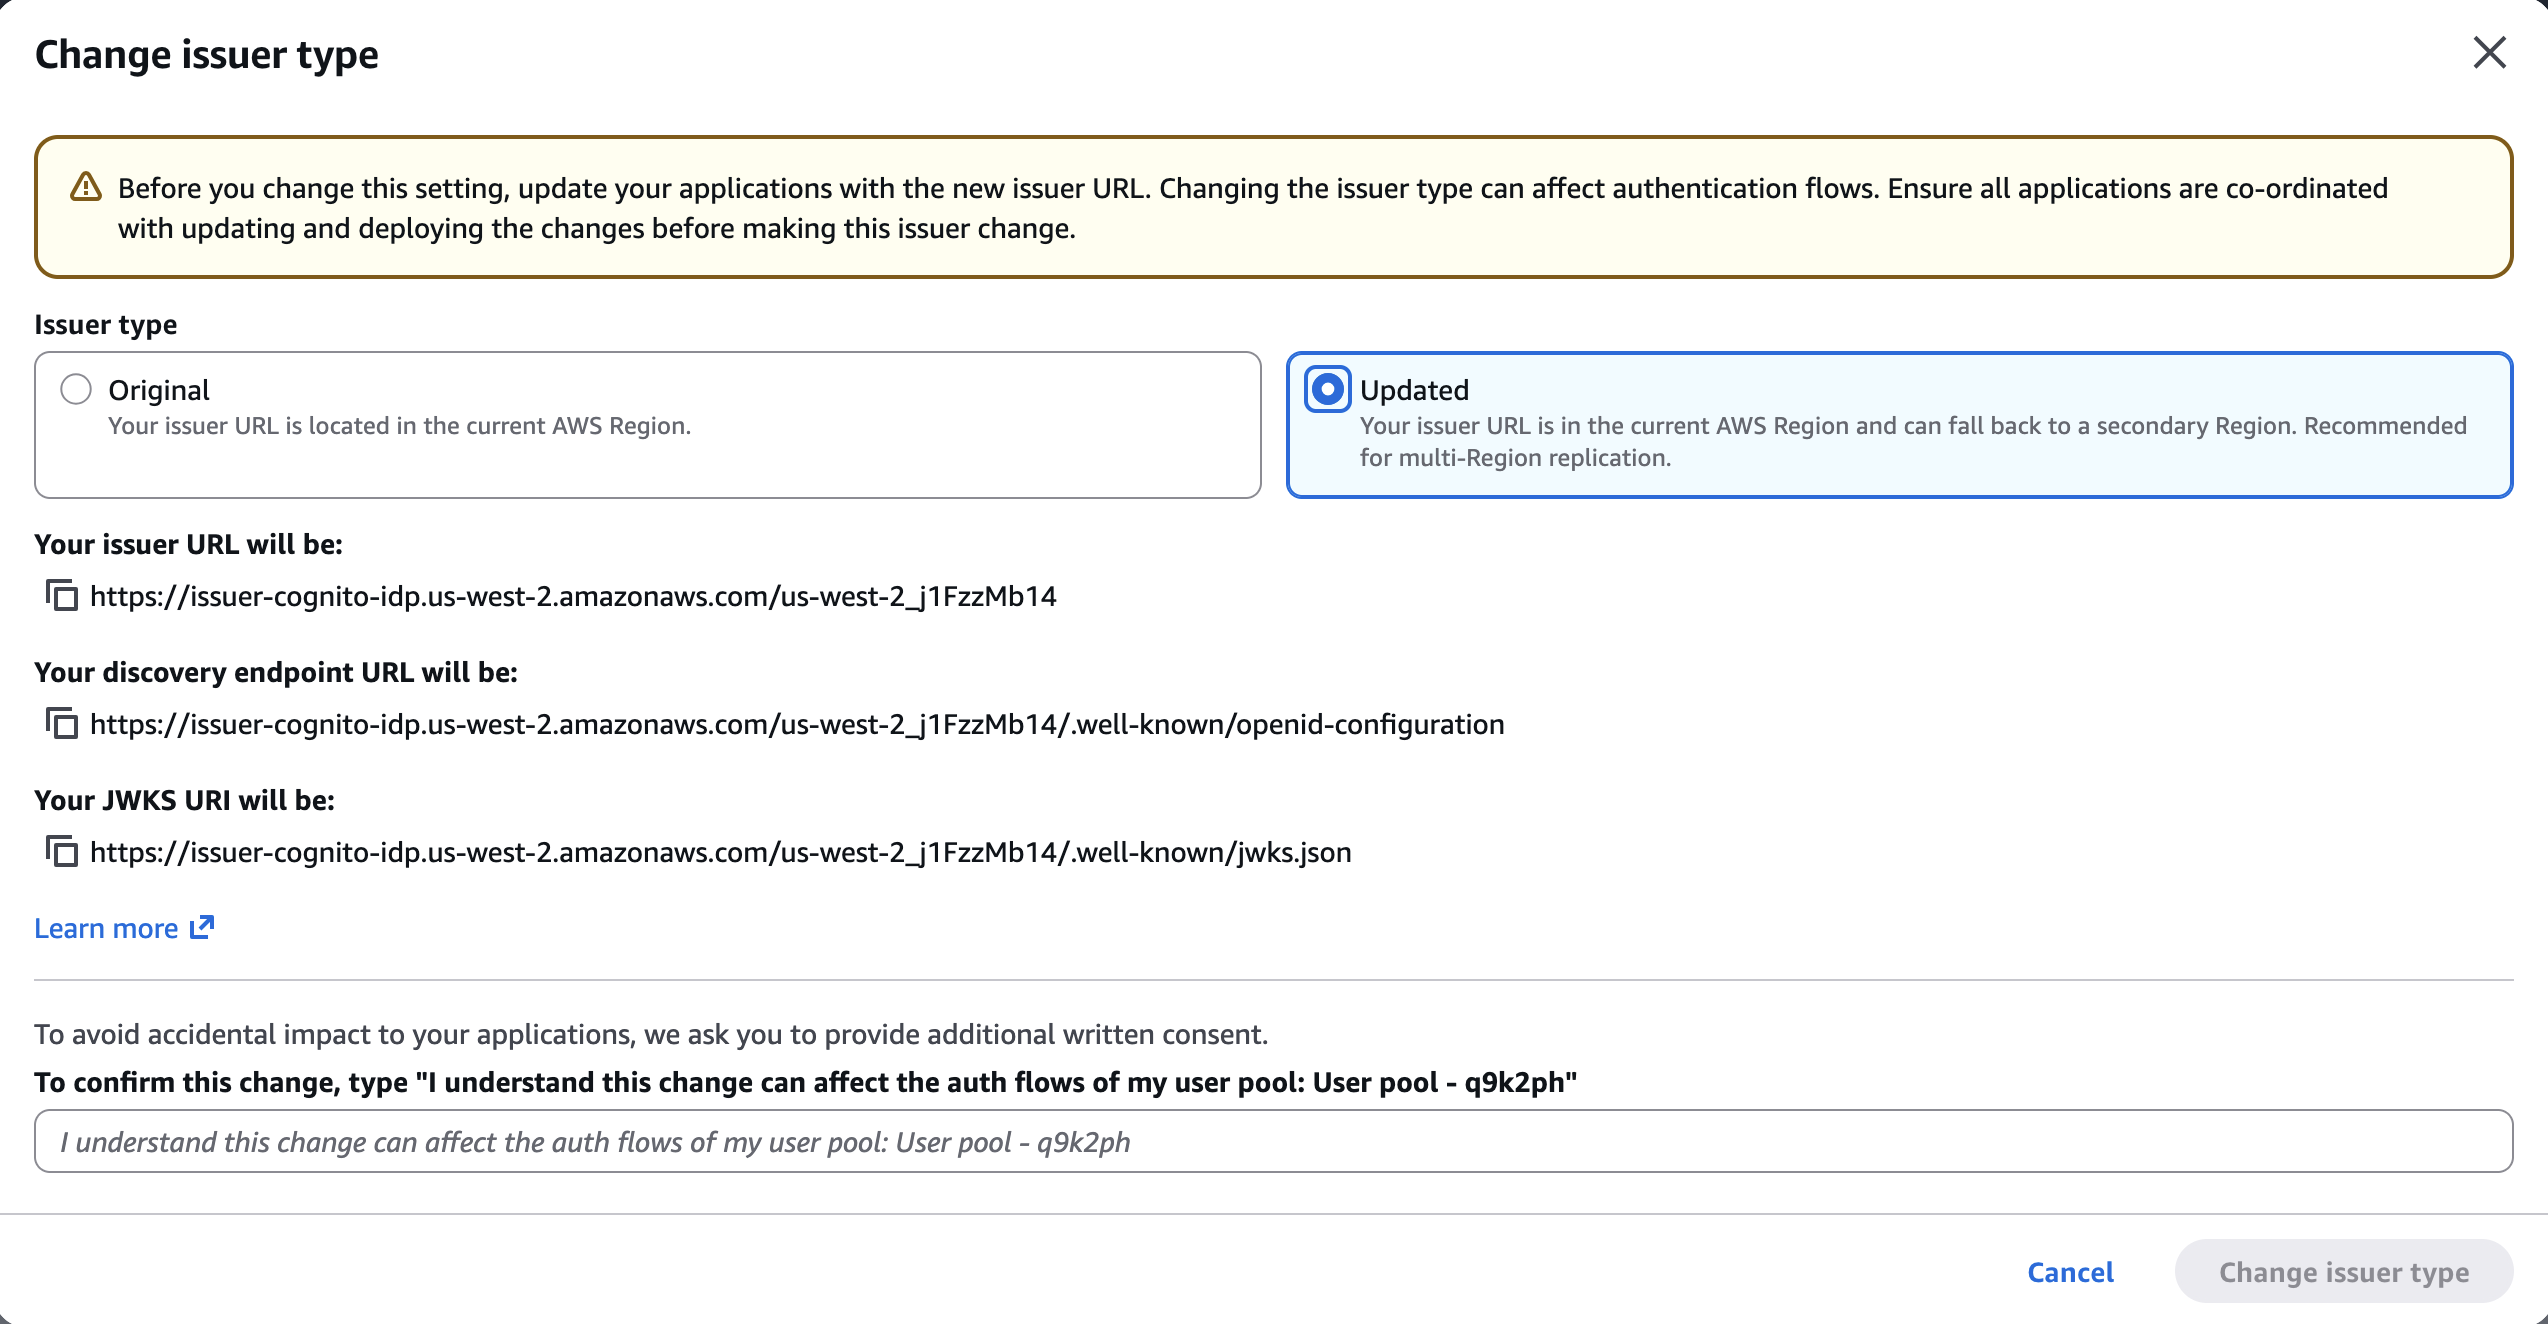
I make sure to update my client applications with these new endpoints. This is a required change that will need a redeployment of server-side applications and an update submission for mobile apps on the App Store and Google Play. If I don’t update the endpoints, my users will experience disruptions because requests to the old endpoints will no longer be routed correctly.

On the next screen, I select Updated. I take note of the new URLs. I confirm the changes and choose Change issuer type.

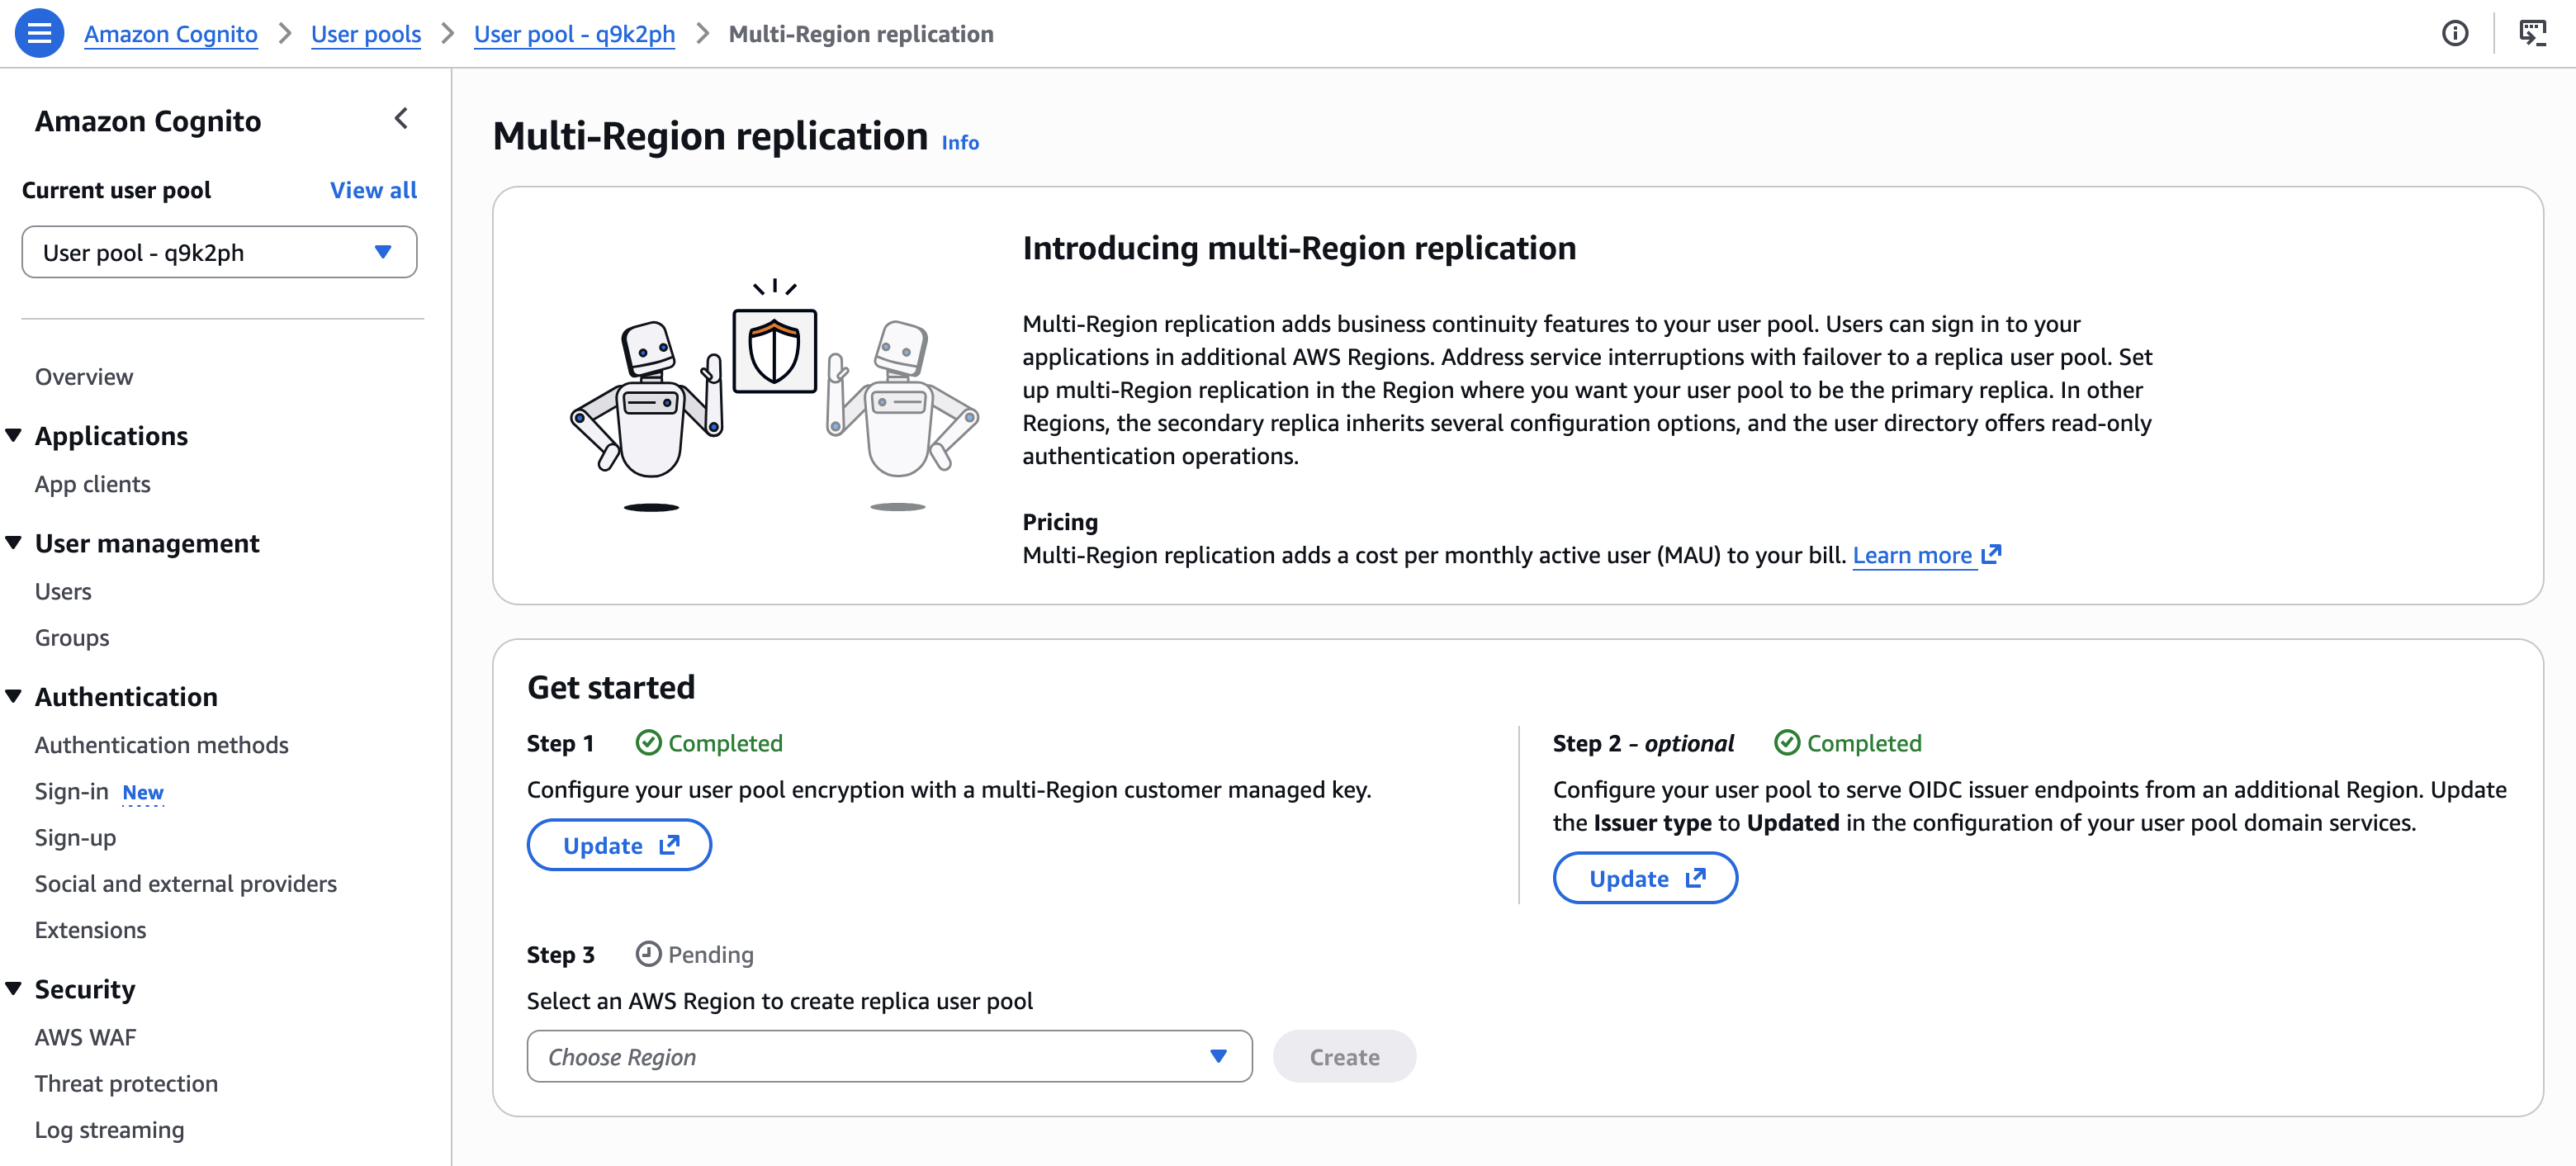
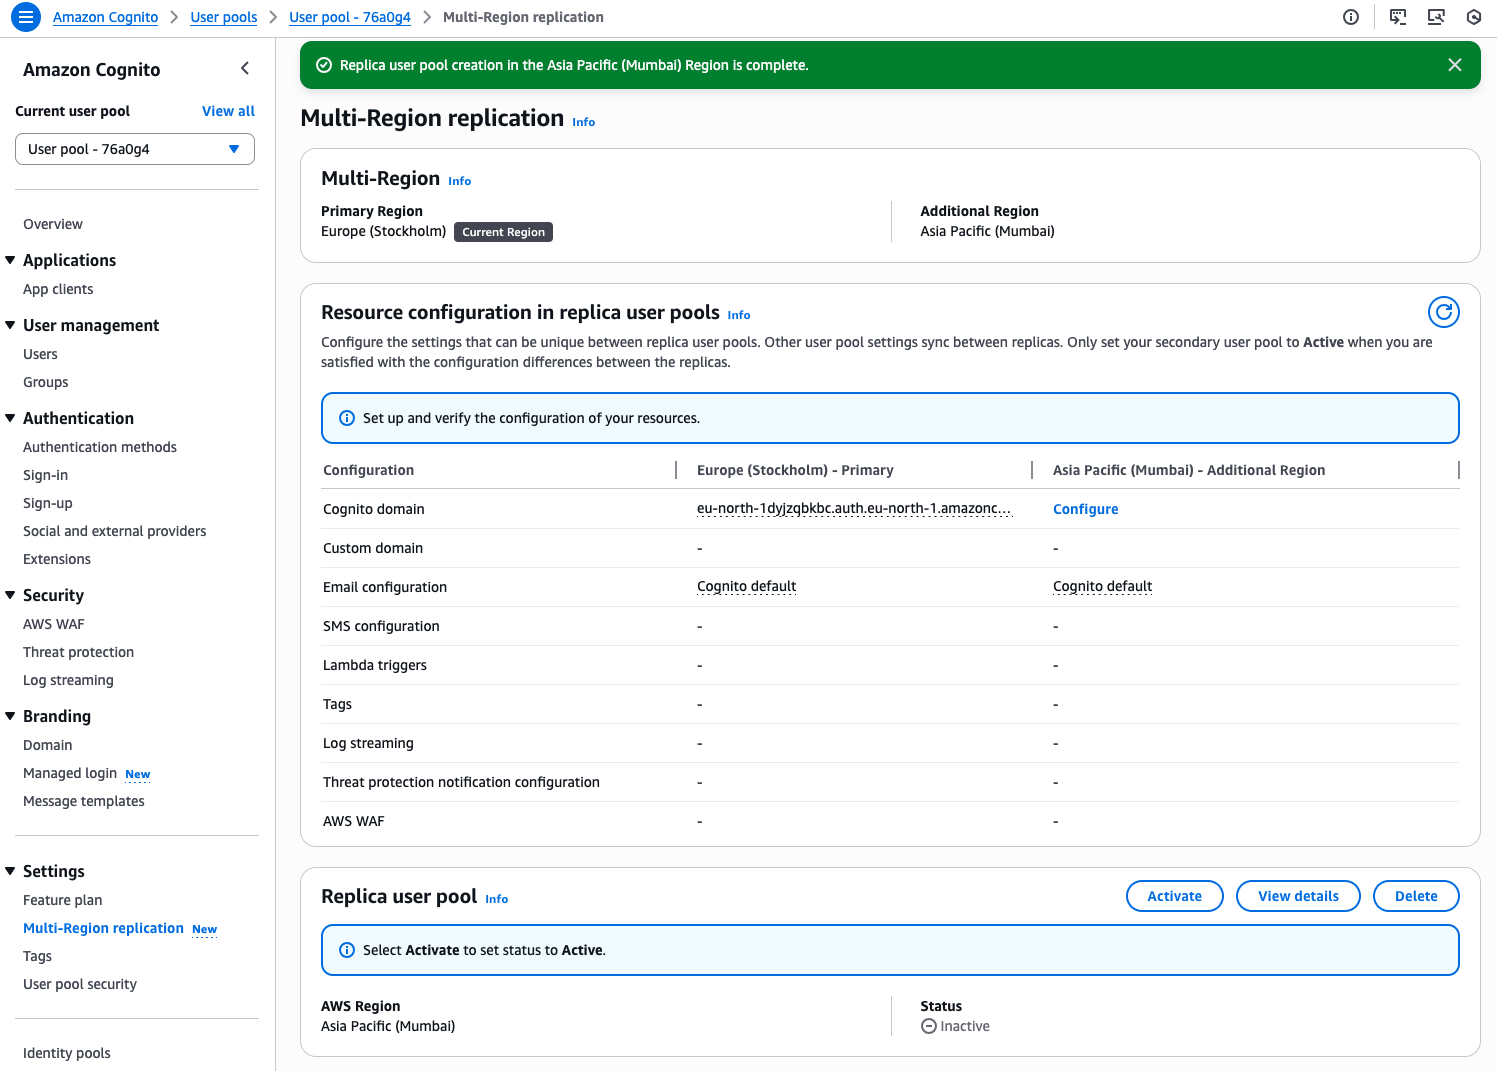
Cognito Multi-Region replication - configure multi region OIDC 2Finally, I select the target Region for replication. Only Regions where the custom encryption key is replicated are available for selection. After having chosen the target Region, I choose Create.Cognito Multi-Region replication - start the replication process.

The service prepares the replication. The time needed depends on the amount of data in the user pool.

When the replicated user pool is ready, I manually Activate it.

Cognito Multi-Region replication - replication process is complete

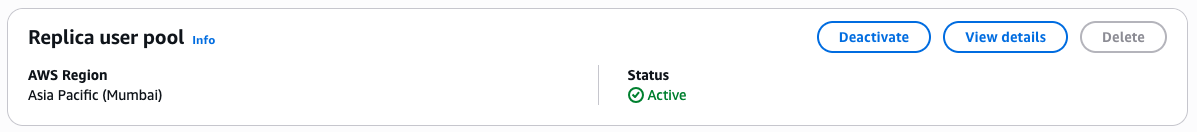
The replication status becomes Active. It is ready to direct traffic to the replica.

Cognito Multi-Region replication - active

Additional configurations
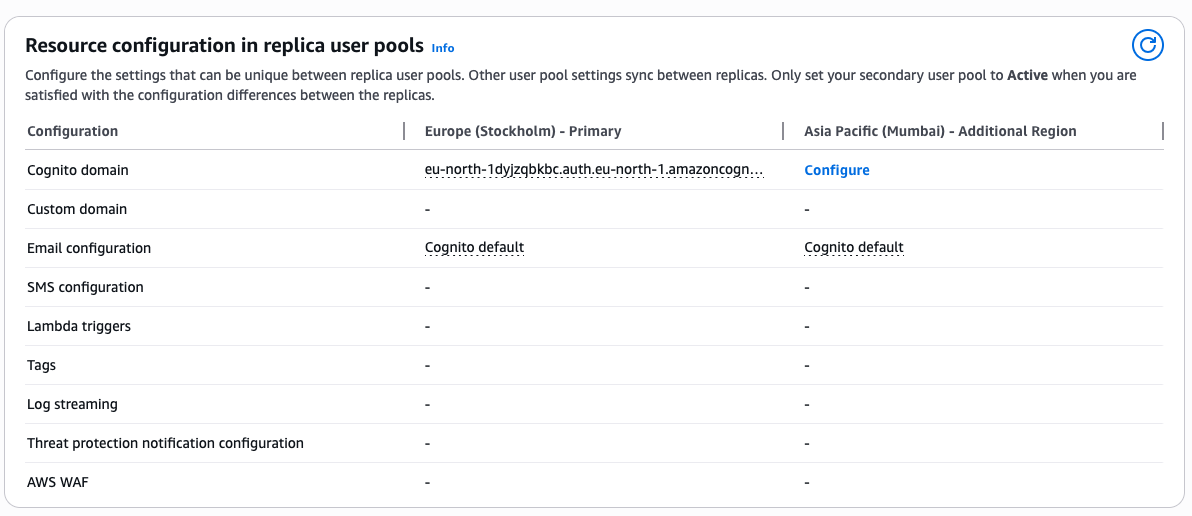
The console helps me to keep track of additional configurations I have to plan. When I’m using Lambda functions for custom authentication flows or SMS or email notifications, I must also deploy and configure these resources in the new Region.

Similarly, log streaming or AWS WAF configuration must be manually configured in the target Region before I start directing authentication traffic to it.

Cognito Multi-Region replication - task list

Health checks and failover
Both primary and secondary regional endpoints remain active and ready to serve your traffic at all times. To monitor system health and manage failovers, you design a strategy that aligns with your application’s specific requirements and security posture. You can implement health checks to monitor the status of authentication services in your primary Region and define criteria for when to initiate failover. These checks might look for error rates, latency patterns, or specific service alerts.

When your monitoring system detects issues meeting your failover criteria, you can redirect traffic to the secondary Region through DNS updates. This approach gives you control over the failover process while maintaining security. Consider testing your failover strategy during off-peak hours by redirecting a small portion of traffic to verify that authentication continues working as expected in the secondary Region.

When using managed login and federation with custom domains, you can also use the built-in traffic routing feature by providing an Amazon Route 53 health check ID.

Pricing and availability
Multi-Region replication is available today as an add-on feature for Amazon Cognito customers using Essentials and Plus tier. For user authentication, the add-on costs $0.0045 per monthly active user per replica Region for Essentials tier customers and $0.006 per monthly active user per replica region for Plus tier customers. For machine-to-machine (M2M) authentication, the add-on is a 30% charge on top of the standard volume-based pricing for successful tokens issued. For detailed pricing information, see Amazon Cognito pricing.

Multi-Region replication is available in the following Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Asia Pacific (Mumbai, Seoul, Singapore, Sydney, Tokyo), Canada (Central), Europe (Frankfurt, Ireland, London, Paris, Stockholm), and South America (São Paulo).

Any of these Regions can be used as the source or the destination for the replication.

Support for customer managed keys is available for the Essentials and Plus tiers. It is available in the following Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Malaysia, Melbourne, Mumbai, New Zealand, Osaka, Seoul, Singapore, Sydney, Thailand, Tokyo), Canada (Central), Canada West (Calgary), Europe (Frankfurt, Ireland, London, Milan, Paris, Spain, Stockholm, Zurich), Israel (Tel Aviv), Mexico (Central), South America (São Paulo), and AWS GovCloud (US-East, US-West)

From my conversations with customers, maintaining business continuity during regional incidents while meeting security requirements is a high priority. Multi-Region replication provides the capability to build more resilient applications without managing complex replication logic yourself. The automatic synchronization of user data and configurations reduces operational overhead while maintaining security.

For customers in regulated industries, the new support for customer managed keys provides additional control over data encryption. You can now use your own encryption keys to protect user data at rest, helping you meet regulatory requirements in industries like healthcare and financial services.

To get started with multi-Region replication and customer managed key encryption, visit the Amazon Cognito console or see the documentation for detailed setup instructions. I look forward to hearing how you use this feature to strengthen your application architecture.

— seb

The AWS MCP Server is now generally available

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/the-aws-mcp-server-is-now-generally-available/

I have been building with AI agents and MCP tools for a while now, and one question kept coming up: how do you give an agent real, authenticated access to AWS without handing it the keys to the kingdom? Today, there is an answer.

I’m happy to announce the general availability of the AWS MCP Server, a managed remote Model Context Protocol (MCP) server that gives AI agents and coding assistants secure, authenticated access to all AWS services through a small, fixed set of tools.

The AWS MCP Server is part of the Agent Toolkit for AWS, a suite of tooling that includes the MCP Server, skills, and plugins that help coding agents build more effectively and efficiently on AWS.

AI coding agents are already useful for many tasks, but they run into real trouble when working with AWS at any meaningful depth. Without access to current AWS documentation, agents rely on training data that may be months out of date and may not know about services like Amazon S3 Vectors, Amazon Aurora DSQL, or Amazon Bedrock AgentCore. When asked to build infrastructure, they tend to reach for the AWS Command Line Interface (AWS CLI) rather than AWS Cloud Development Kit (AWS CDK) or AWS CloudFormation, and they produce AWS Identity and Access Management (IAM) policies that are far broader than necessary. The result is infrastructure that works in a demo but is not production-ready.

The AWS MCP Server addresses this through a compact set of tools that do not consume your model’s context window. The call_aws tool executes any of the 15,000+ AWS API operations using your existing IAM credentials. When we will launch new APIs, they will be supported within days. The search_documentation and read_documentation tools retrieve current AWS documentation and best practices at query time, so the agent always works from up-to-date information.

With general availability, we are introducing several new capabilities. The AWS MCP Server now supports IAM context keys, so you no longer need a separate IAM permission to use the server and can express fine-grained access in a standard IAM policy. Documentation retrieval no longer requires authentication. We have also reduced the number of tokens required per interaction, which matters for complex, multi-step workflows.

Also new, the run_script tool lets the agent write a short Python script that runs server-side in a sandboxed environment. The sandbox inherits your IAM permissions but has no network access, so you can give an agent the ability to process data without giving it access to your local file system or a shell. When an agent needs to call multiple APIs and combine the results, making them one at a time is slow and burns context. With run_script, the agent chains API calls, filters responses, and computes results in a single round-trip, which is both faster and more context-efficient.

The most significant addition is the transition from Agent SOPs to Skills. Skills provide curated guidance and best practices for the tasks where agents most commonly make mistakes. This helps agents complete work faster, using validated best practices, with fewer errors and fewer tokens — all of which saves you time and money. Skills are contributed and maintained by AWS service teams. This keeps the tool list short and predictable, which reduces hallucination and keeps the agent focused.

For enterprise customers, the AWS MCP Server provides a clear separation between human and agent permissions. You can use IAM policies or Service Control Policies to specify that a given user can perform mutating operations while the MCP server is restricted to read-only actions. Amazon CloudWatch metrics published under the AWS-MCP namespace let you observe MCP server calls separately from direct human calls, giving you the audit trail that compliance teams require. Amazon CloudTrail captures all API calls for a complete record.

Let’s see it in action
For this demo, I chose to use Claude Code, but I can use the AWS MCP Server with any AI agent that supports MCP, which is basically all tools available today: Kiro CLI, Kiro, Cursor, Codex, and more. I configure Claude Code to use the Anthropic Opus 4.6 model.

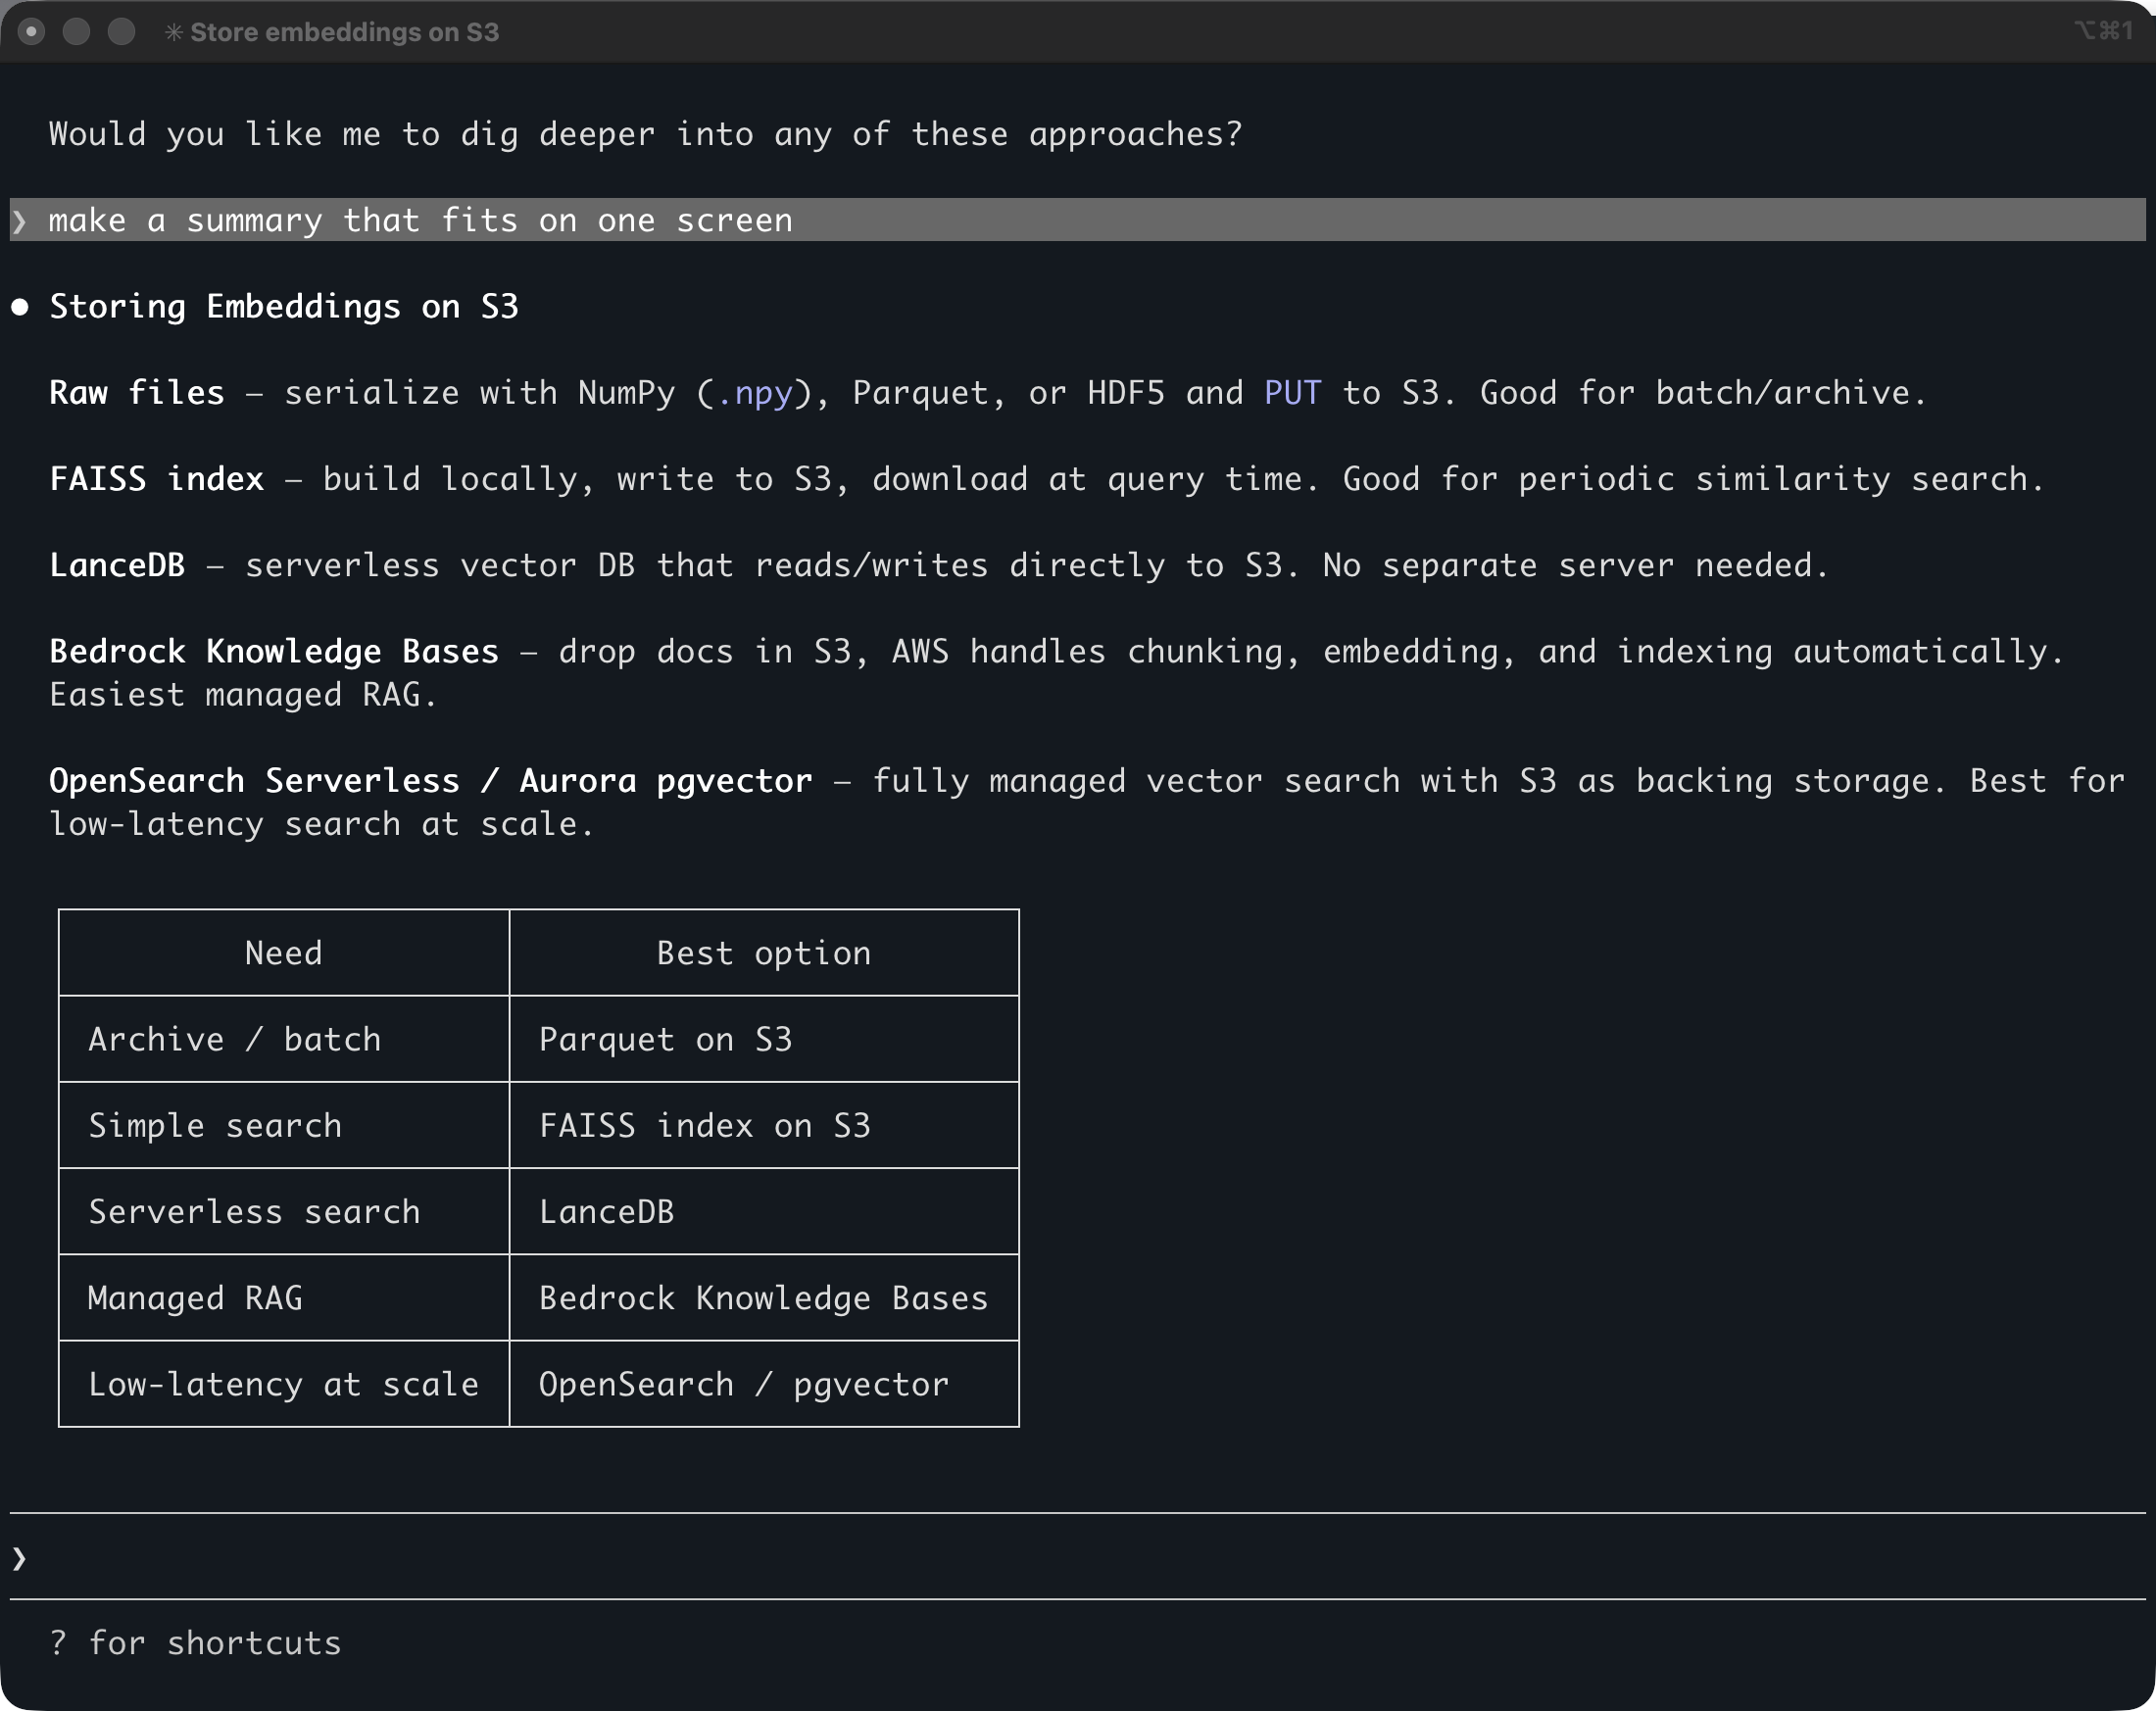
Opus 4.6 has a knowledge cutoff date in May 2025. It means it doesn’t know anything that happened after May last year. I ask a question about an AWS service that was introduced recently: Amazon S3 Vectors, launched in preview in July 2025 and that went GA in December 2025.

The question is “how to store embedding on S3″. (embedding is a kind of vector)

It gives me five solutions, all correct, but none using S3 Vectors as I asked. Note that this answer comes from the Opus 4.6 model, not from Claude Code. Any AI tool using the same model will return similar answers because S3 Vectors wasn’t announced at the time the model was trained.

Claude Code response about S3 Vectors with Opus 4.6 and no AWS MCP Server

Let’s now try with the AWS MCP Server.

The AWS MCP Server uses AWS Identity and Access Management (IAM) and IAM SigV4 authentication. To use my local AWS credentials configuration over MCP, which only supports OAuth 2.1, I configure my AI coding agent to call the AWS MCP Server through a proxy. The MCP Proxy for AWS is an open source proxy that runs on my machine and bridges the world of IAM authentication to OAuth.

I add the MCP configuration with this command:

claude mcp add-json aws-mcp --scope user \
   '{"command":"uvx","args":["mcp-proxy-for-aws@latest","https://aws-mcp.us-east-1.api.aws/mcp","--metadata","AWS_REGION=us-west-2"]}'

Let’s analyze the JSON configuration:

  • I use the user scope to make the server available to all my projects on my laptop.
  • uvx mcp-proxy-for-aws is the command to launch the proxy; the rest of the arguments are parameters passed to the proxy.
  • https://aws-mcp.us-east-1.api.aws/mcp is one of the two regional endpoints for the AWS MCP Server. The proxy will forward Claude Code’s requests to that endpoint.
  • --metadata are passed to the proxy target. Here, it tells the AWS MCP Server to use the US West (Oregon) Region.

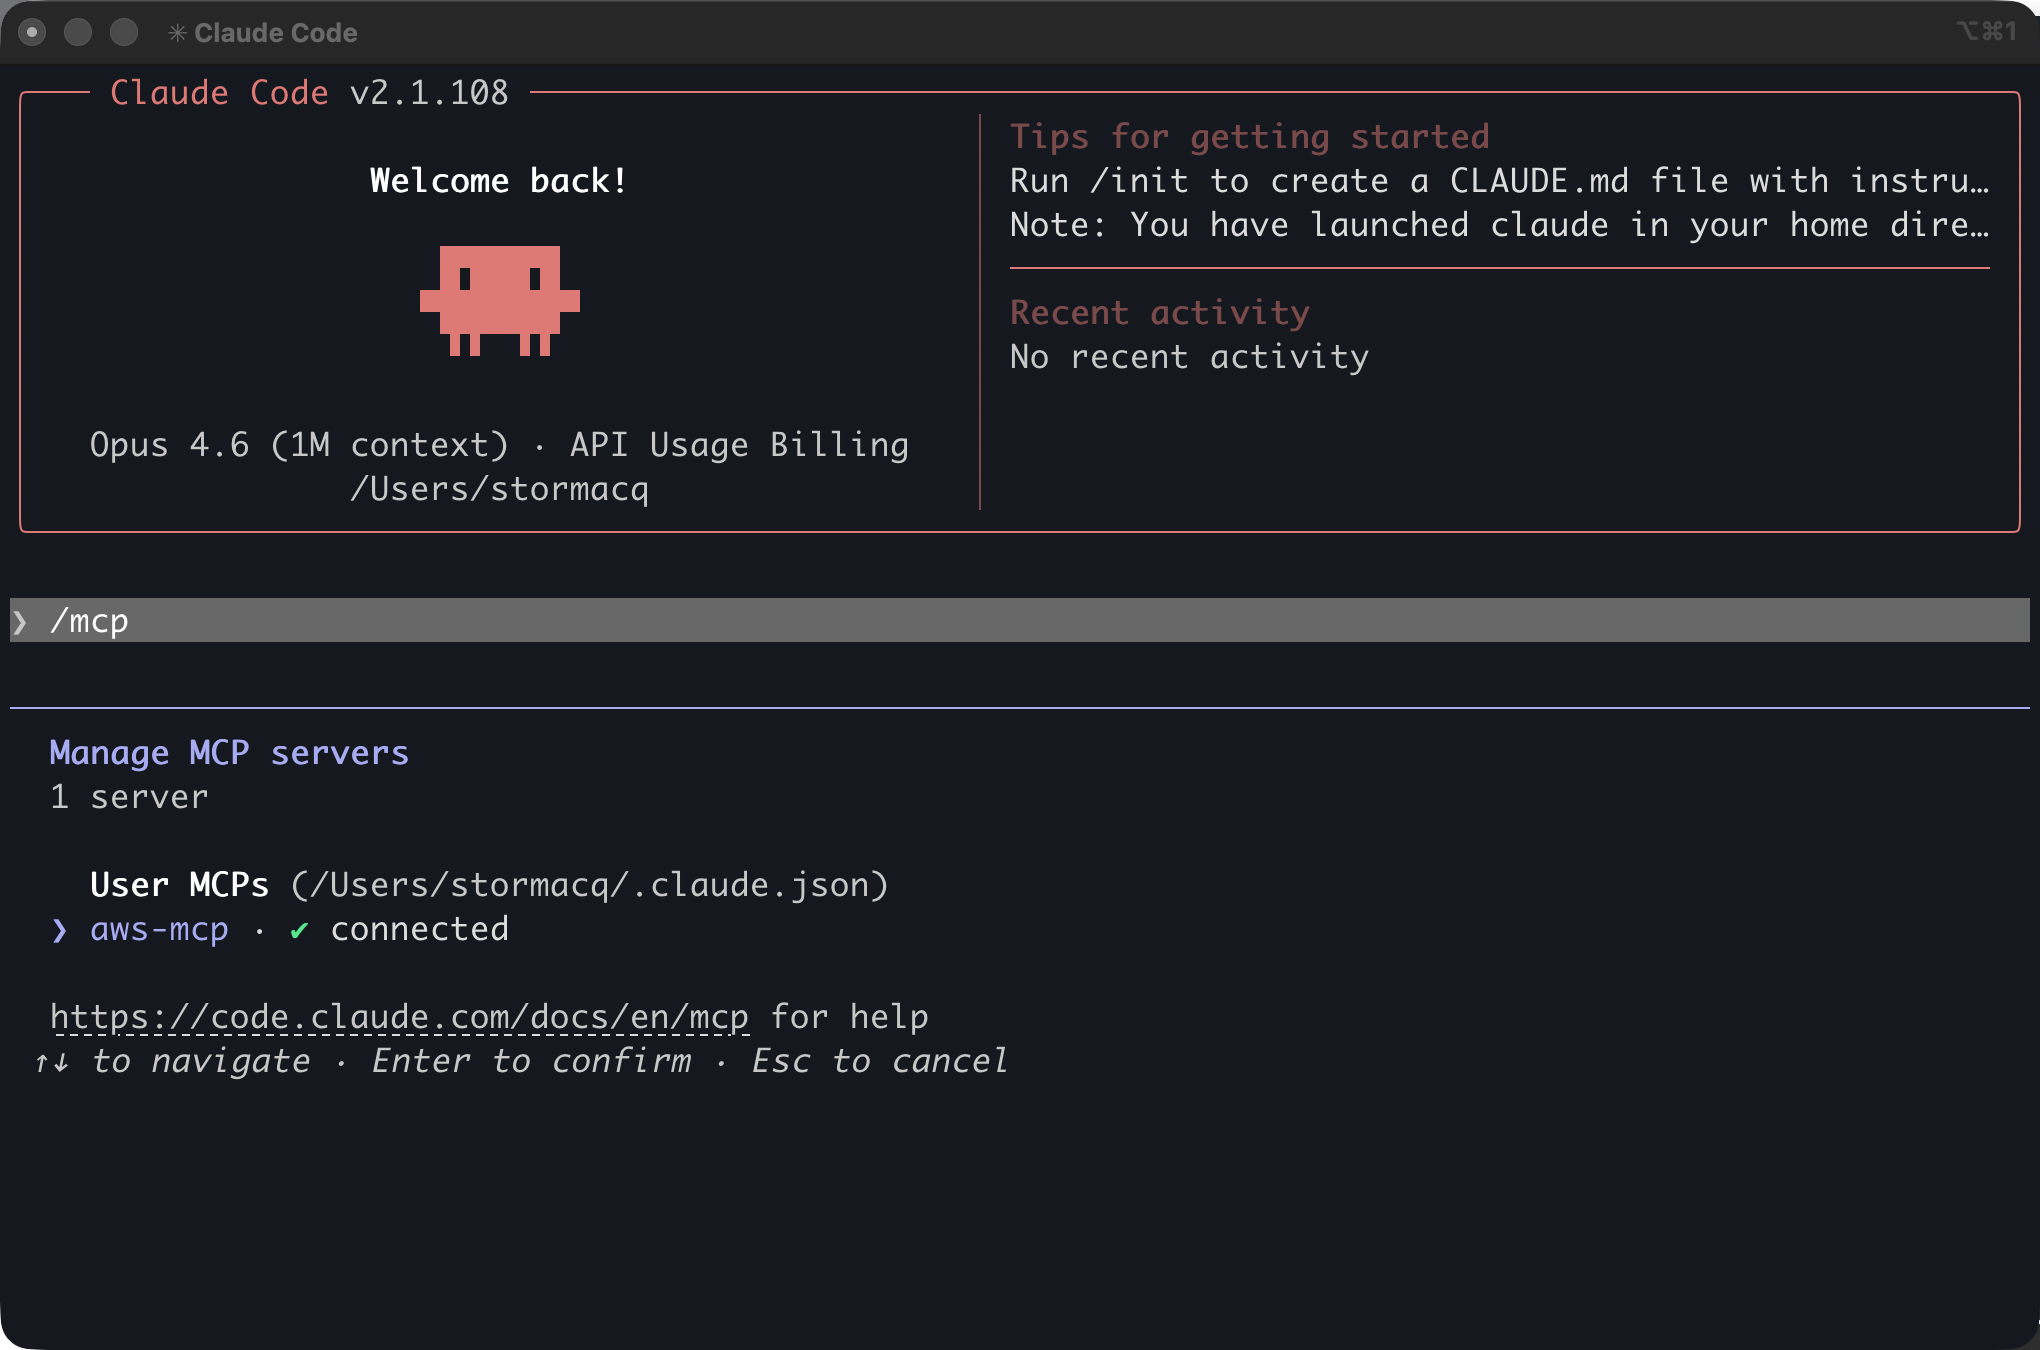
I start Claude Code and I type /mcp to verify the AWS MCP Server is correctly installed and can use my credentials.

Verify AWS MCP Server in Claude Code

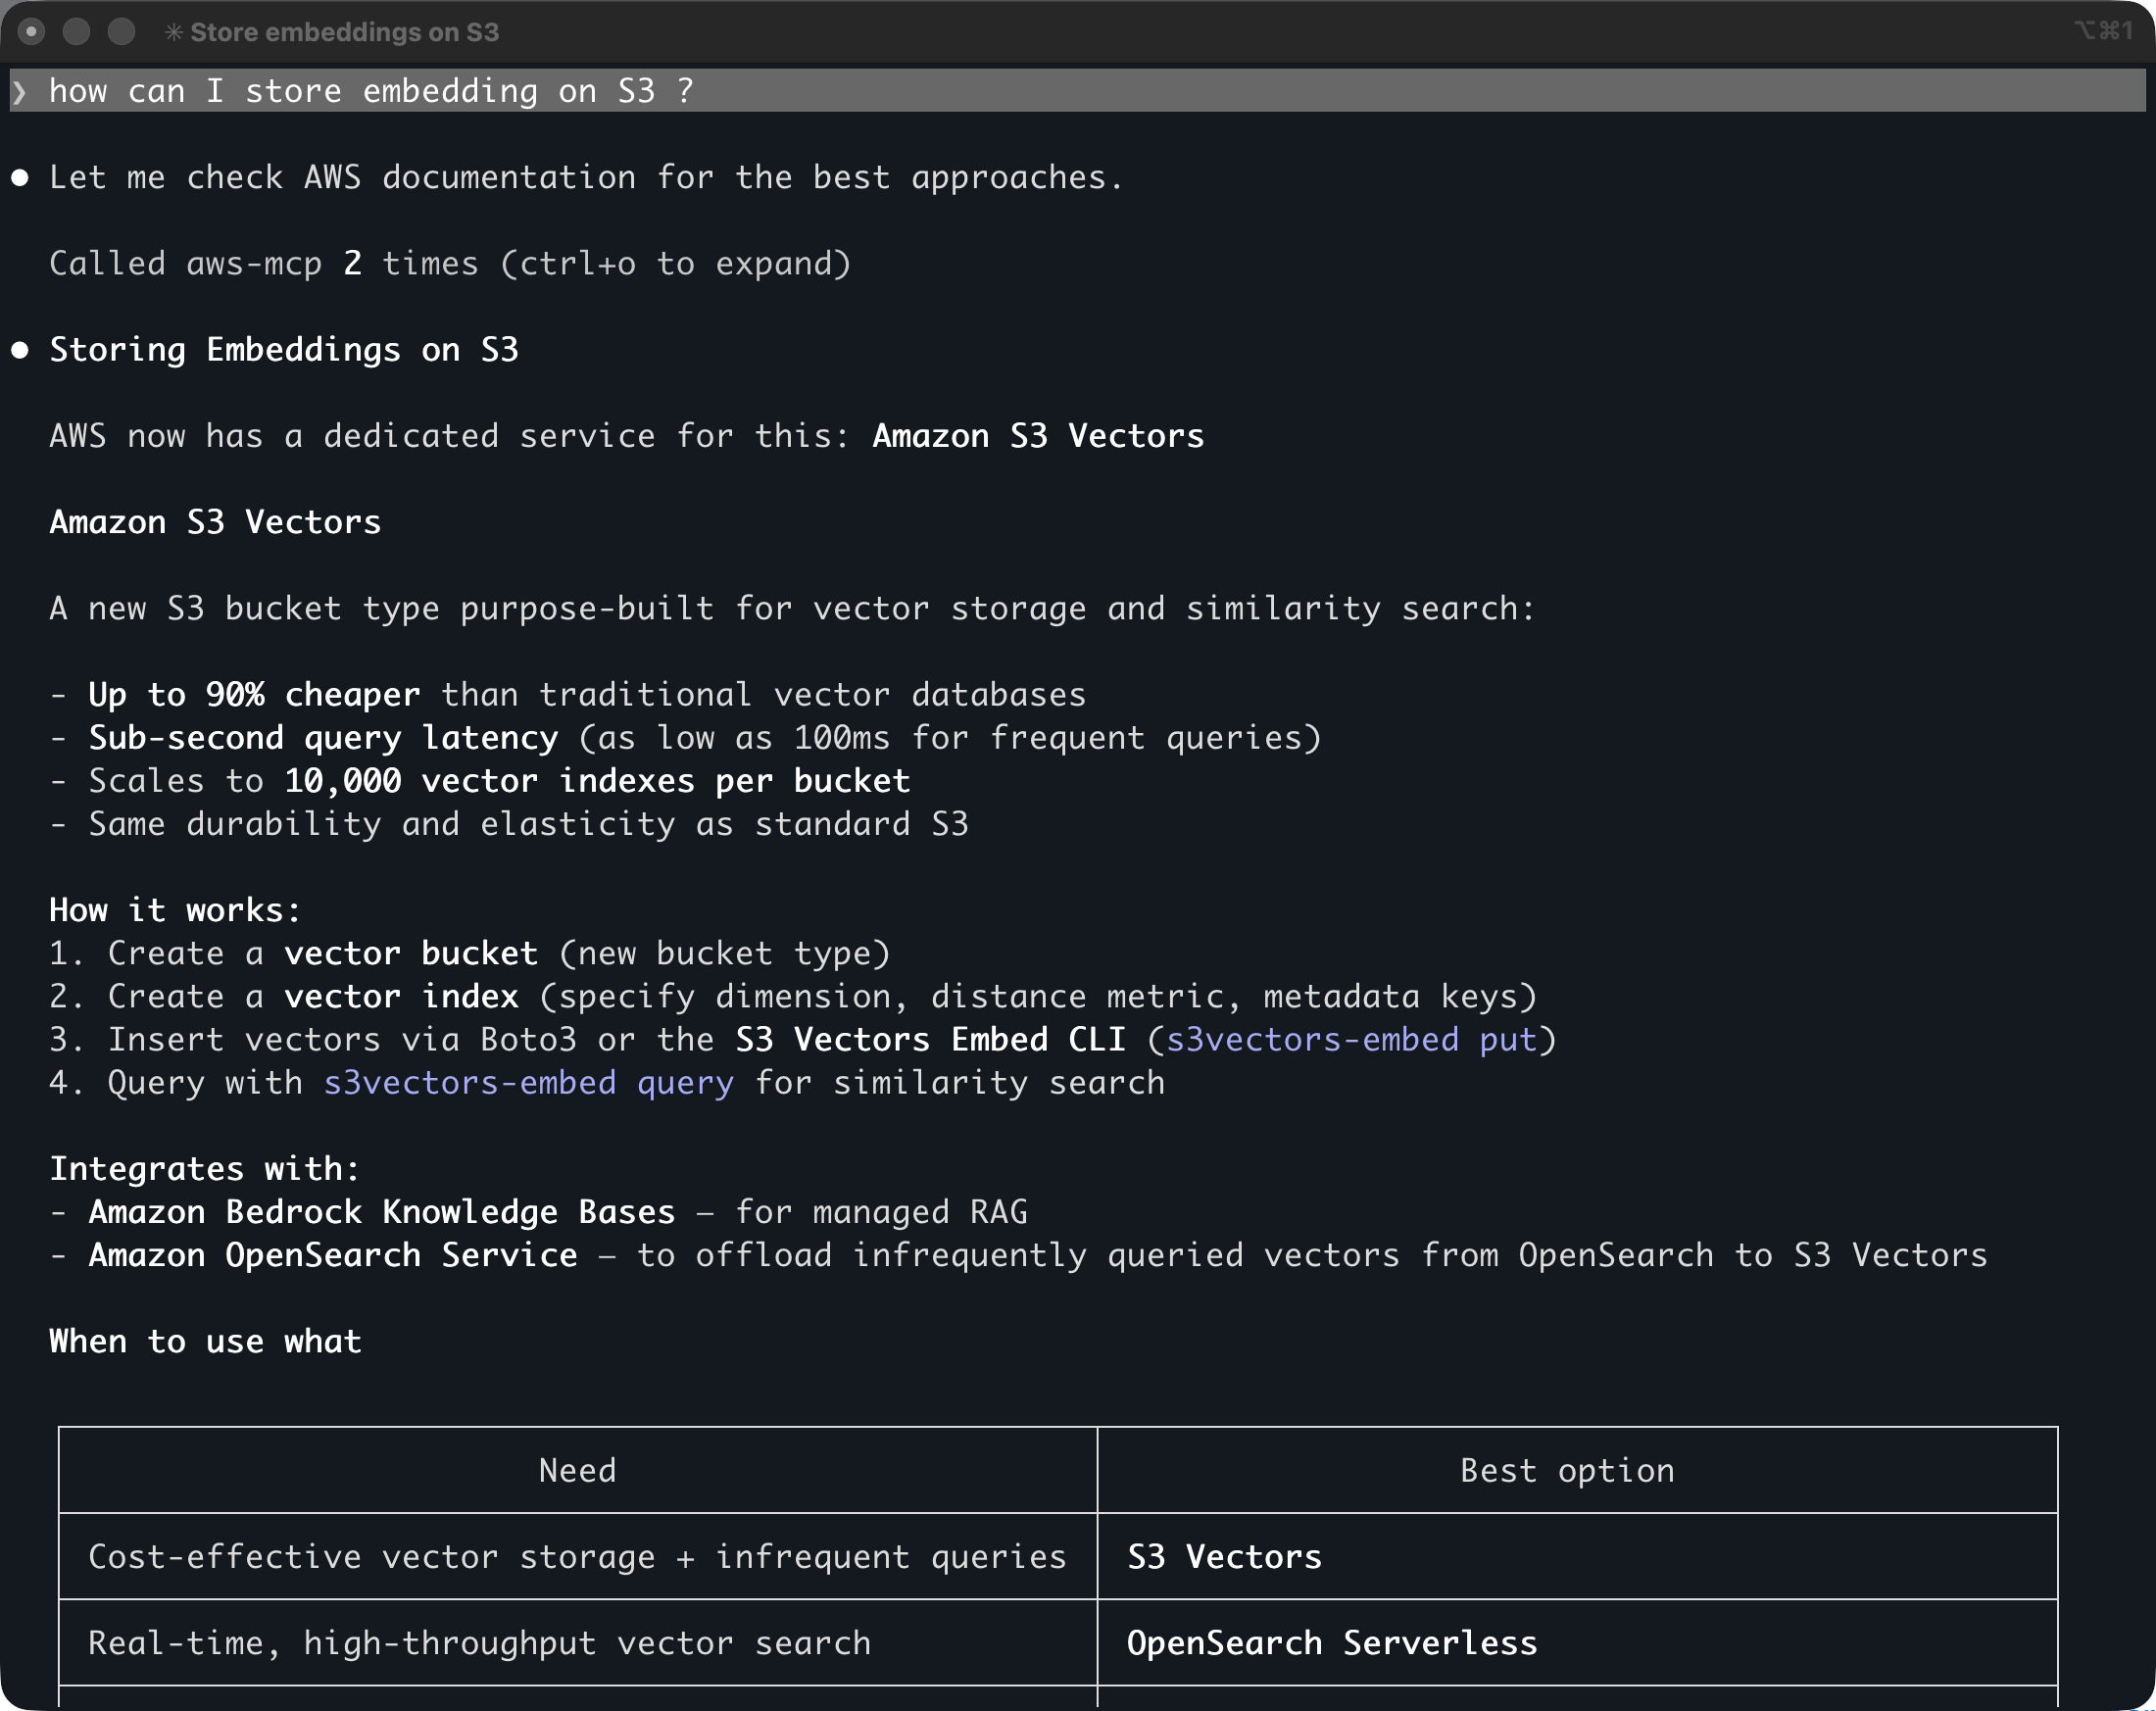
I ask the same question: “how can I store embedding on S3”.

This time, Claude Code knows it has a tool it can use to answer the question. It asks me permission to invoke the aws___search_documentation tool. After a few seconds, I receive a correct answer: “AWS now has a dedicated service for this: Amazon S3 Vectors …”

Claude Code correct response about S3 Vectors

Pricing and availability
The AWS MCP Server is available today in the US East (N. Virginia) and Europe (Frankfurt) AWS Regions and can make API calls to any Region. There is no additional charge for the AWS MCP server itself. You pay only for the AWS resources you create and any applicable data transfer costs.

The AWS MCP Server works with Claude Code, Kiro, Cursor, and any MCP-compatible client. To get started, see the AWS MCP Server User Guide.

I have been waiting for something like this since I started using MCP tools in my AI agents early last year. The combination of current documentation, authenticated API access, and sandboxed script execution in a single server changes what an agent can actually do on AWS. I am curious what you build with it. Let me know in the comments.

— seb

AWS Weekly Roundup: Claude Opus 4.7 in Amazon Bedrock, AWS Interconnect GA, and more (April 20, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-7-in-amazon-bedrock-aws-interconnect-ga-and-more-april-20-2026/

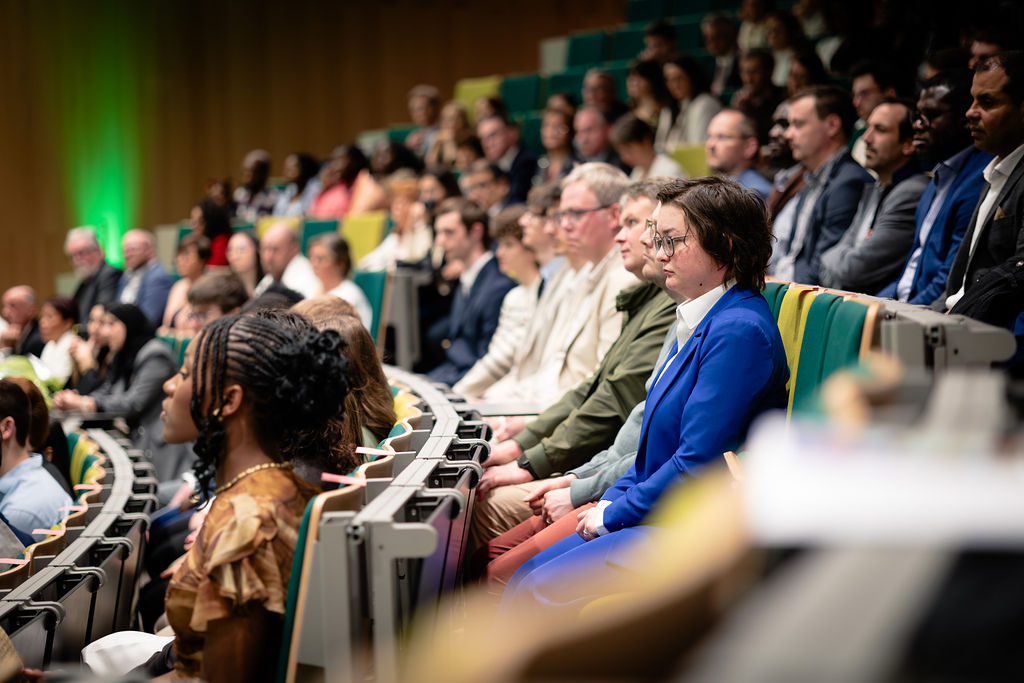
Last week I had the honor of delivering a commencement speech at the University of Namur (uNamur) for their 2025 graduation ceremony.

uNamur Graduation Ceremony

Standing in front of freshly minted computer science graduates, I talked about the future of software development in the age of AI. My message to them was simple: AI will not make you obsolete. We’ve seen tools evolve over the decades, from punch cards to IDEs to AI-assisted coding, but the work remains yours, not the tool’s. The developers who will thrive are those who stay curious, think in systems, communicate with precision, and take ownership of what they build. The world needs more people with coding skills, not fewer. AI raises the bar on what we can accomplish, and that’s a good thing.

Now, let’s get into this week’s AWS news.

Headlines
Anthropic’s Claude Opus 4.7 is now available in Amazon Bedrock – Anthropic’s most intelligent Opus model is now available in Amazon Bedrock, with improved performance across coding, long-running agents, and professional knowledge work. Claude Opus 4.7 scores 64.3% on SWE-bench Pro and 87.6% on SWE-bench Verified, extending its lead in agentic coding with stronger long-horizon autonomy and complex code reasoning. It also does better on knowledge work tasks like document creation, financial analysis, and multi-step research.

The model runs on Bedrock’s next-generation inference engine with dynamic capacity allocation, adaptive thinking (letting Claude allocate thinking token budgets based on request complexity), and the full 1M token context window. It also adds high-resolution image support for better accuracy on charts, dense documents, and screen UIs. Claude Opus 4.7 is available at launch in US East (N. Virginia), Asia Pacific (Tokyo), Europe (Ireland), and Europe (Stockholm), with up to 10,000 requests per minute per account per Region.

AWS Interconnect is now generally available with a new option to simplify last-mile connectivity – AWS Interconnect brings two managed private connectivity capabilities to general availability. The first, AWS Interconnect – Multicloud, provides Layer 3 private connections between AWS VPCs and other cloud providers (Google Cloud available now, Azure and OCI coming later in 2026). Traffic flows over the AWS global backbone and the partner cloud’s private network, never over the public internet, with built-in MACsec encryption, multi-facility resiliency, and CloudWatch monitoring. AWS published the underlying specification on GitHub under Apache 2.0 so any cloud provider can become an Interconnect partner.

The second capability, AWS Interconnect – Last Mile, simplifies high-speed private connections from branch offices, data centers, and remote locations to AWS through existing network providers. It provisions 4 redundant connections across 2 physical locations automatically, configures BGP routing, activates MACsec encryption and Jumbo Frames by default, and offers bandwidth from 1 Gbps to 100 Gbps adjustable from the console without reprovisioning. Last Mile launches in US East (N. Virginia) with Lumen as the initial partner.

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Amazon ECR pull through cache now supports referrer discovery and sync — ECR’s pull through cache now automatically discovers and syncs OCI referrers (image signatures, SBOMs, attestations) from upstream registries into your private repositories. This means end-to-end image signature verification and SBOM discovery workflows work without client-side workarounds.
  • AWS Transform is now available in Kiro and VS Code — AWS Transform, the agentic migration and modernization factory, is now accessible via Kiro (as a Power) and VS Code (as an extension). You can run custom transformations for common patterns like Java/Python/Node.js version upgrades and AWS SDK migrations directly from your IDE, with job state shared across the web console, CLI, and IDE.
  • Aurora DSQL launches connector for PHP — A new Aurora DSQL Connector for PHP (PDO_PGSQL) simplifies building PHP applications on Aurora DSQL by automatically generating IAM tokens, handling SSL configuration, managing connection pooling, and providing opt-in optimistic concurrency control retry with exponential backoff.
  • Amazon Q supports document-level access controls for Google Drive — Amazon Q now enforces document-level access controls for Google Drive knowledge bases, combining indexed ACL replication for fast pre-retrieval filtering with real-time permission checks against Google Drive at query time.
  • AWS Secrets Manager now supports hybrid post-quantum TLS — Secrets Manager now supports hybrid post-quantum key exchange using ML-KEM to protect secrets against both current and future quantum computing threats. This is automatically enabled in Secrets Manager Agent 2.0.0+, Lambda Extension v19+, and the CSI Driver 2.0.0+.
  • Amazon EC2 C8in and C8ib instances are now generally available — Powered by custom 6th-gen Intel Xeon Scalable processors and 6th-gen AWS Nitro cards, these instances deliver up to 43% higher performance over C6in. C8in offers 600 Gbps network bandwidth (highest among enhanced networking EC2 instances), while C8ib delivers up to 300 Gbps EBS bandwidth (highest among non-accelerated compute instances), scaling up to 384 vCPUs.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Navigating enterprise networking challenges with Amazon EKS Auto Mode — This post explains how EKS Auto Mode automates Kubernetes networking infrastructure including VPC CNI configuration, load balancer provisioning, and DNS management, reducing operational overhead while preserving enterprise security controls.
  • Introducing granular cost attribution for Amazon Bedrock — My colleague Micah talked about this feature last week already, but the blog post came out after last week’s roundup. Amazon Bedrock now automatically attributes inference costs to the specific IAM principal that made each API call, with results flowing into AWS Cost and Usage Reports (CUR 2.0). You can aggregate costs by team, project, or cost center using IAM principal tags and session tags.
  • Accelerate development workflows with Amazon EBS Volume Clones — EBS Volume Clones let you create instant, point-in-time copies of EBS volumes that are immediately usable without waiting for data transfer. The post highlights use cases including dev/test environment refreshes, disaster recovery testing, and CI/CD pipeline acceleration.
  • Modernize VB6 applications at scale with AWS Transform Custom — A walkthrough of using AWS Transform Custom’s agentic AI capabilities to convert legacy Visual Basic 6.0 applications to modern C# ASP.NET Core web applications, addressing challenges like COM dependencies, ADO-to-Entity Framework migration, and VB6 forms-to-Blazor UI conversion.
  • Migrating and decomposing APIs with zero-downtime using CloudFront — A zero-downtime API migration strategy using CloudFront Functions with CloudFront KeyValueStore for intelligent, user-aware traffic routing based on the Strangler Fig pattern. This is similar to what AWS Migration Hub Refactor Spaces offers, but implemented with just CloudFront and edge functions.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Events — Browse upcoming AWS-led in-person and virtual events, startup events, and developer-focused events near you.
  • AWS Power Hour — Weekly live training sessions on Twitch covering various AWS topics.
  • Community.aws — Find community-led events, meetups, and user groups in your area.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

AWS Interconnect is now generally available, with a new option to simplify last-mile connectivity

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-interconnect-is-now-generally-available-with-a-new-option-to-simplify-last-mile-connectivity/

Today, we’re announcing the general availability of AWS Interconnect – multicloud, a managed private connectivity service that connects your Amazon Virtual Private Cloud (Amazon VPC) directly to VPCs on other cloud providers. We’re also introducing AWS Interconnect – last mile, a new capability that simplifies how you establish high-speed, private connections to AWS from your branch offices, data centers, and remote locations through your existing network providers.

Large enterprises increasingly run workloads across multiple cloud providers, whether to use specialized services, meet data residency requirements, or support teams that have standardized on different providers. Connecting those environments reliably and securely has historically required significant coordination: managing VPN tunnels, working with colocation facilities, and configuring third-party network fabrics. The result is that your networking team spends time on undifferentiated heavy lifting instead of focusing on the applications that matter to your business.

AWS Interconnect is the answer to these challenges. It is a managed connectivity service that simplifies connectivity into AWS. Interconnect provides you the ability to establish private, high-speed network connections with dedicated bandwidth to and from AWS across hybrid and multicloud environments. You can configure resilient, end-to-end connectivity with ease in a few clicks through the AWS Console by selecting your location, partner, or cloud provider, preferred Region, and bandwidth requirements, removing the friction of discovering partners and the complexity of manual network configurations.

It comes with two capabilities: multicloud connectivity between AWS and other cloud providers, and last-mile connectivity between AWS and your private on-premises networks. Both capabilities are built on the same principle: a fully managed, turnkey experience that removes the infrastructure complexity from your team.

AWS Interconnect – multicloud
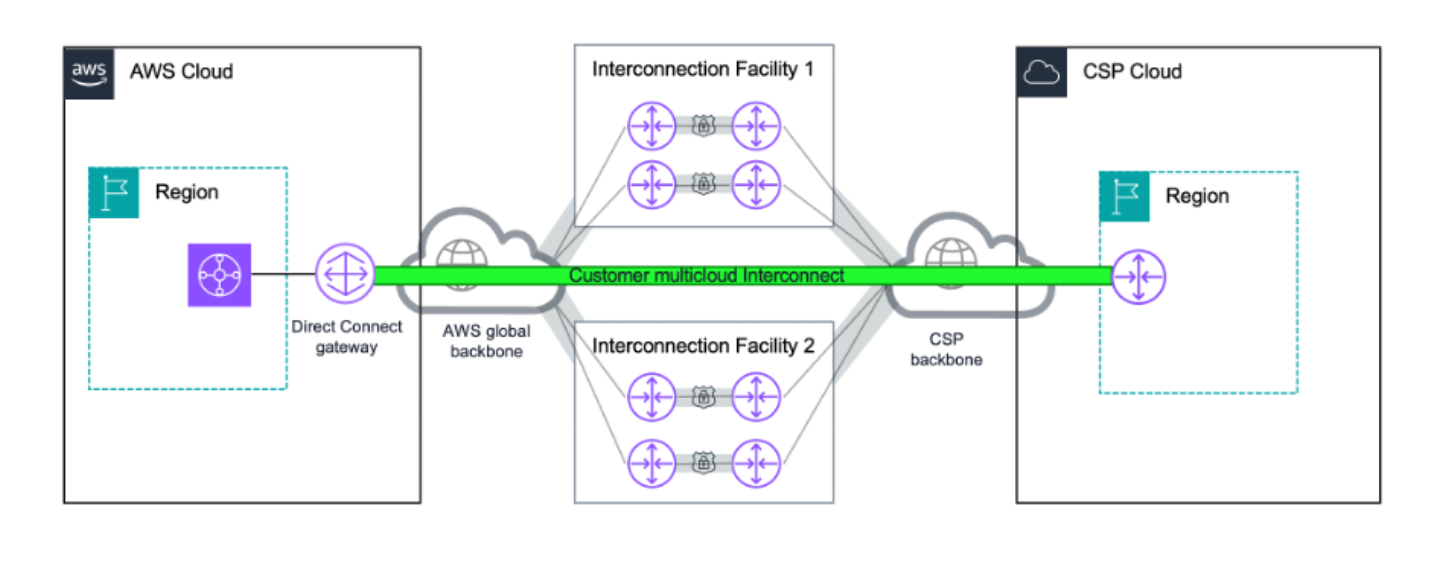
AWS Interconnect – multicloud gives you a private, managed Layer 3 connection between your AWS environment and other cloud providers, starting with Google Cloud, and Microsoft Azure coming later in 2026. Traffic flows entirely over the AWS global backbone and the partner cloud’s private network, so it never traverses the public internet. This means you get predictable latency, consistent throughput, and isolation from internet congestion without having to manage any physical infrastructure yourself.

Security is built in by default. Every connection uses IEEE 802.1AE MACsec encryption on the physical links between AWS routers and the partner cloud provider’s routers at the interconnection facilities. You don’t need to configure these separately. Note that each cloud provider manages encryption independently on its own backbone, so you should review the encryption documentation for your specific deployment to verify it meets your compliance requirements. Resiliency is also built in: each connection spans multiple logical links distributed across at least two physical facilities, so a single device or building failure does not interrupt your connectivity.

AWS Interconnect - multicloud - architectureFor monitoring, AWS Interconnect – multicloud integrates with Amazon CloudWatch. You get a Network Synthetic Monitor included with each connection to track round-trip latency and packet loss, and bandwidth utilization metrics to support capacity planning.

AWS has published the underlying specification on GitHub under the Apache 2.0 license, providing any cloud service provider the opportunity to collaborate with AWS Interconnect – multicloud. To become an AWS Interconnect partner, cloud providers must implement the technical specification and meet AWS operational requirements, including resiliency standards, support commitments, and service level agreements.

How it works
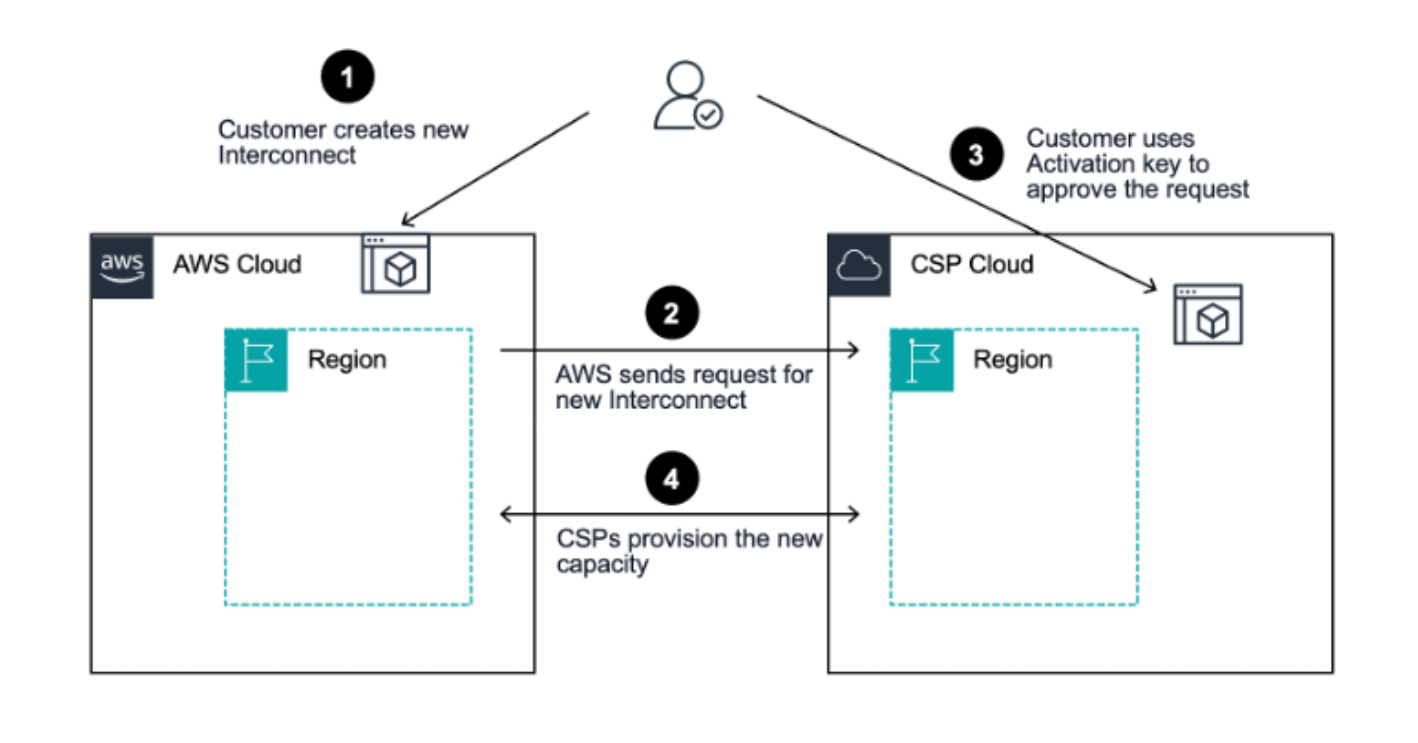
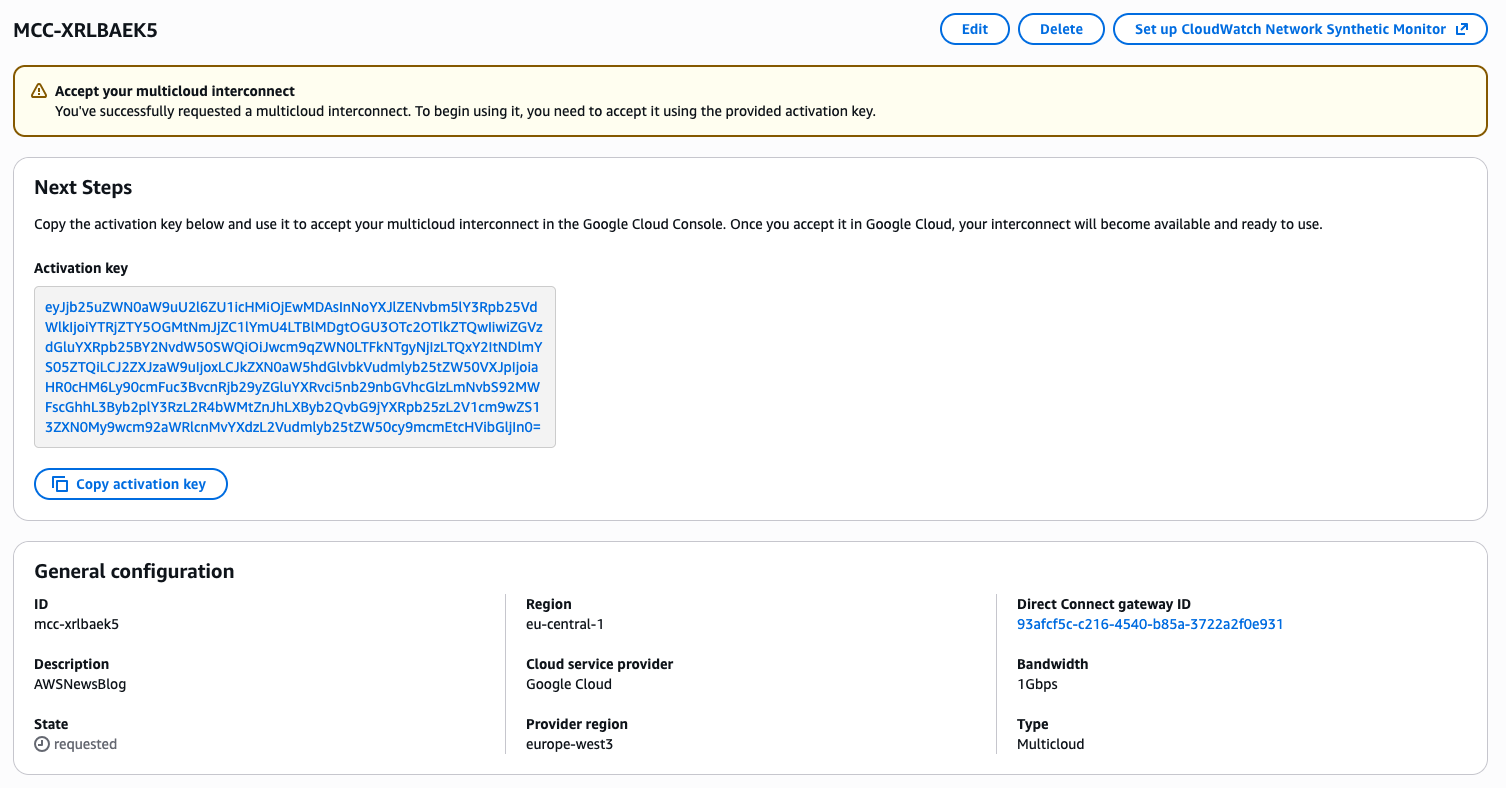
Provisioning a connection takes minutes. I create the connection from the AWS Direct Connect console. I start from the AWS Interconnect section and select Google Cloud as the provider. I select my source and destination regions. I specify bandwidth, and provide my Google Cloud project ID. AWS generates an activation key that I use on the Google Cloud side to complete the connection. Routes propagate automatically in both directions, and my workloads can start exchanging data shortly after.

AWS INterconnect - multicloud - provisionningFor this demo, I start with a single VPC and I connect it to a Google Cloud VPC. I use a Direct Connect Gateway. It’s the simplest path: one connection, one attachment, and my workloads on both sides can start talking to each other in minutes.

Step 1: request an interconnect in the AWS Management Console.

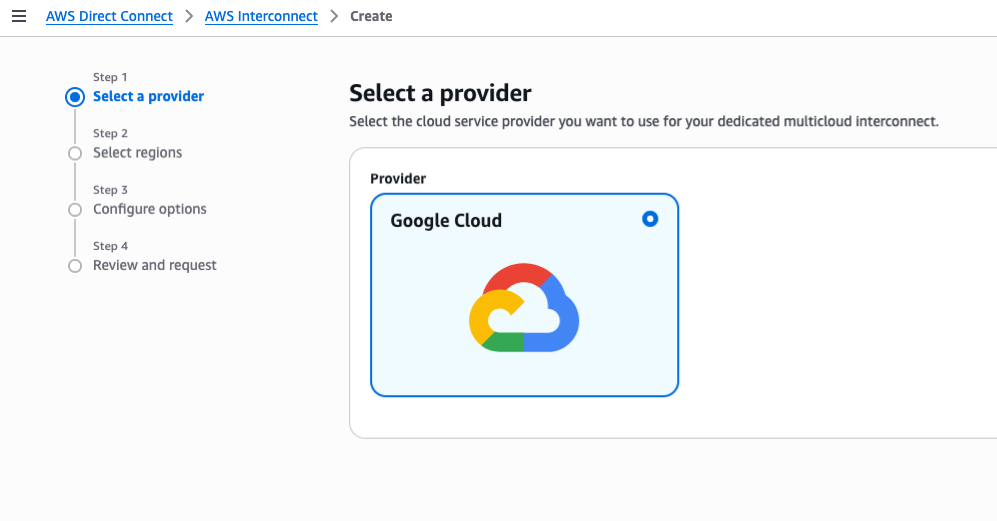
I navigate to AWS Direct Connect, AWS Interconnect and I select Create. I first choose the cloud provider I want to connect to. In this example, Google Cloud.

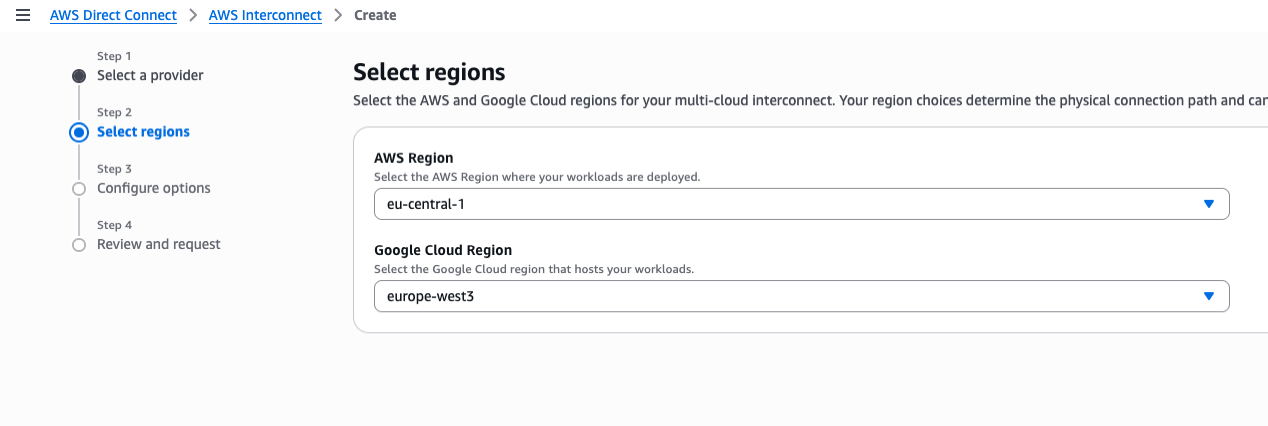
AWS interconnect - 1Then, I choose the AWS Region (eu-central-1) and the Google Cloud Region (europe-west3).

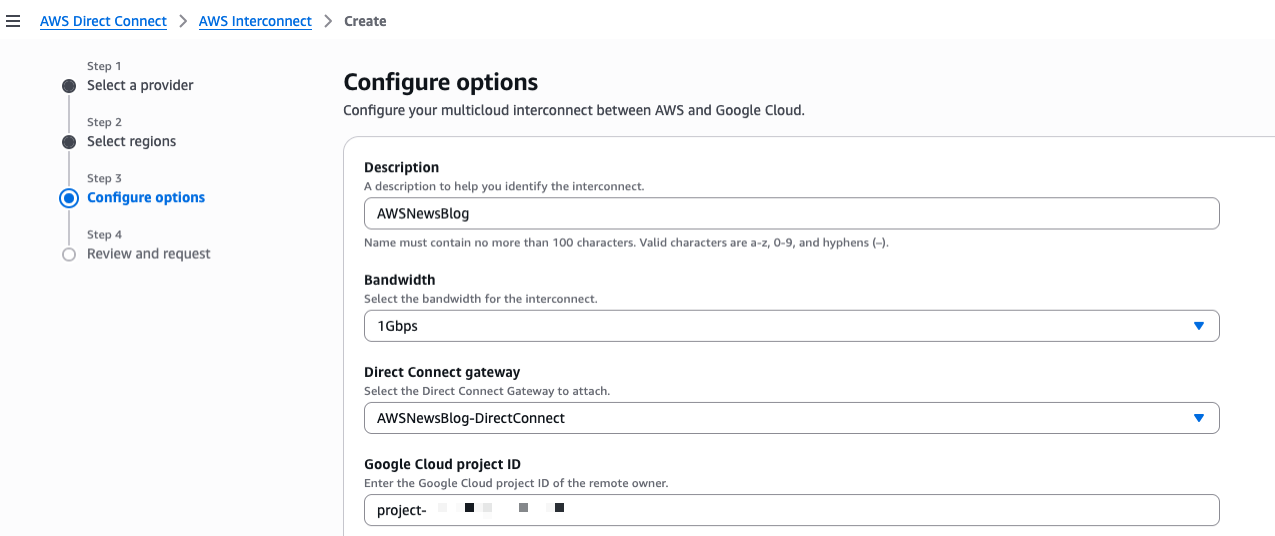
AWS interconnect - 2On step 3, I enter Description,I choose the Bandwidth, the Direct Connect gateway to attach, and the ID of my Google Cloud project.

AWS interconnect - 3

After reviewing and confirming the request, the console gives me an activation key. I will use that key to validate the request on the Google cloud side.

AWS interconnect - 4

Step 2: create the transport and VPC Peering resources on my Google Cloud Platform (GCP) account.

Now that I have the activation key, I continue the process on the GCP side. At the time of this writing, no web-based console was available. I choose to use the GCP command line (CLI) instead. I take note of the CIDR range in the GCP VPC subnet in the europe-west3 region. Then, I open a Terminal and type:

gcloud network-connectivity transports create aws-news-blog \
    --region=europe-west3  \
    --activation-key=${ACTIVATION_KEY} \
    --network=default \
    --advertised-routes=10.156.0.0/20

Create request issued for: [aws-news-blog]
...
peeringNetwork: projects/oxxxp-tp/global/networks/transport-9xxxf-vpc
...
state: PENDING_CONFIG
updateTime: '2026-03-19T09:30:51.103979219Z'

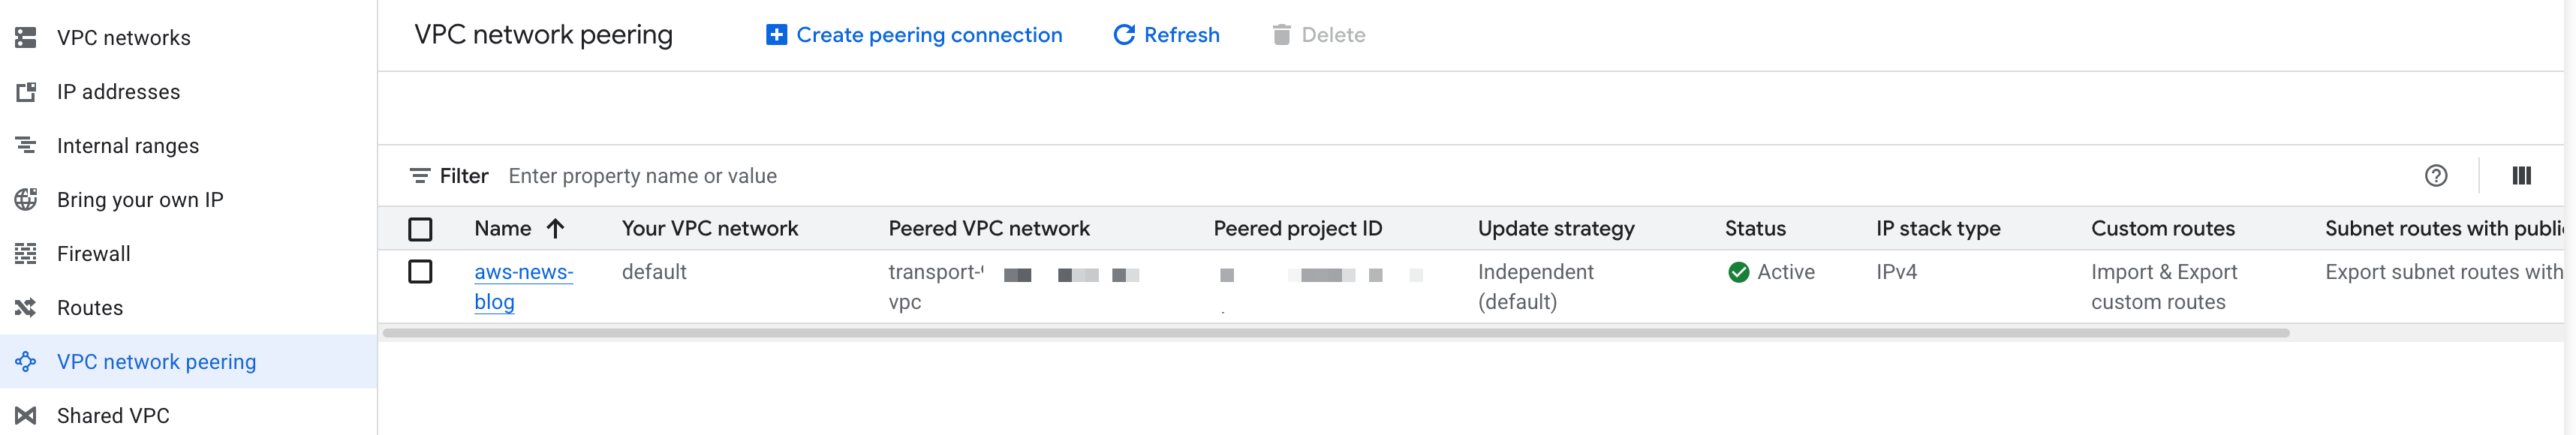
It takes a couple of minutes for the command to complete. Once the command returns, I create a peering between my GCP VPC and the new transport I just created. I can do that in the GCP console or with the gcloud command line. Because I was using the Terminal for the previous command, I continued with the command line:

gcloud compute networks peerings create aws-news-blog \
      --network=default \
      --peer-network=projects/oxxxp-tp/global/networks/transport-9xxxf-vpc \
      --import-custom-routes \
      --export-custom-routes

The network name is the name of my GCP VPC. The peer network is given in the output of the previous command.

Once completed, I can verify the peering in the GCP console.
AWS Interconnect - Peering in the Google console

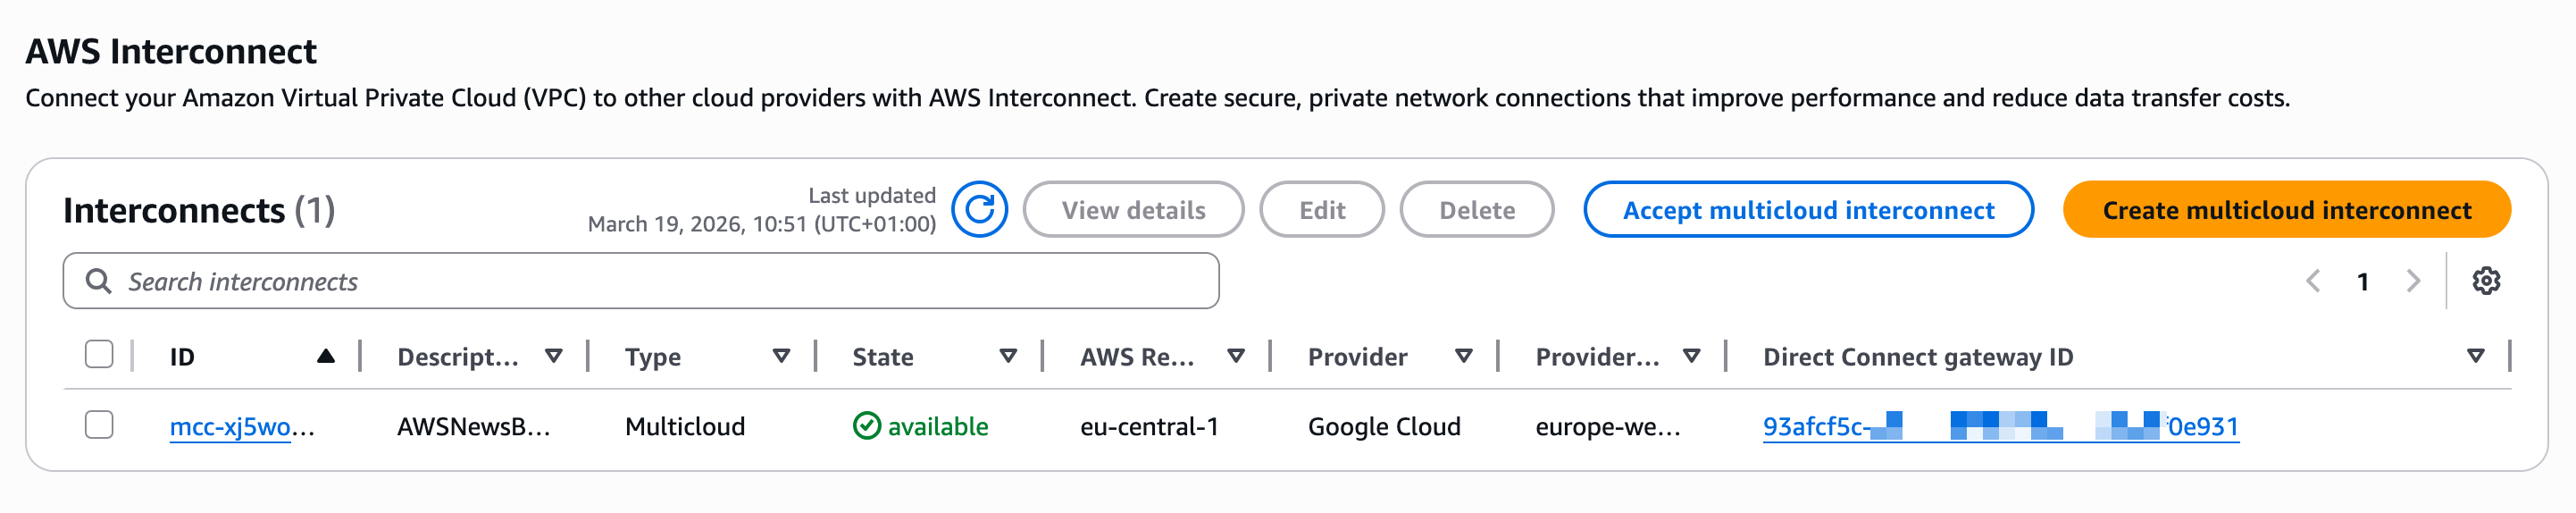
In the AWS Interconnect console, I verify the status is available.

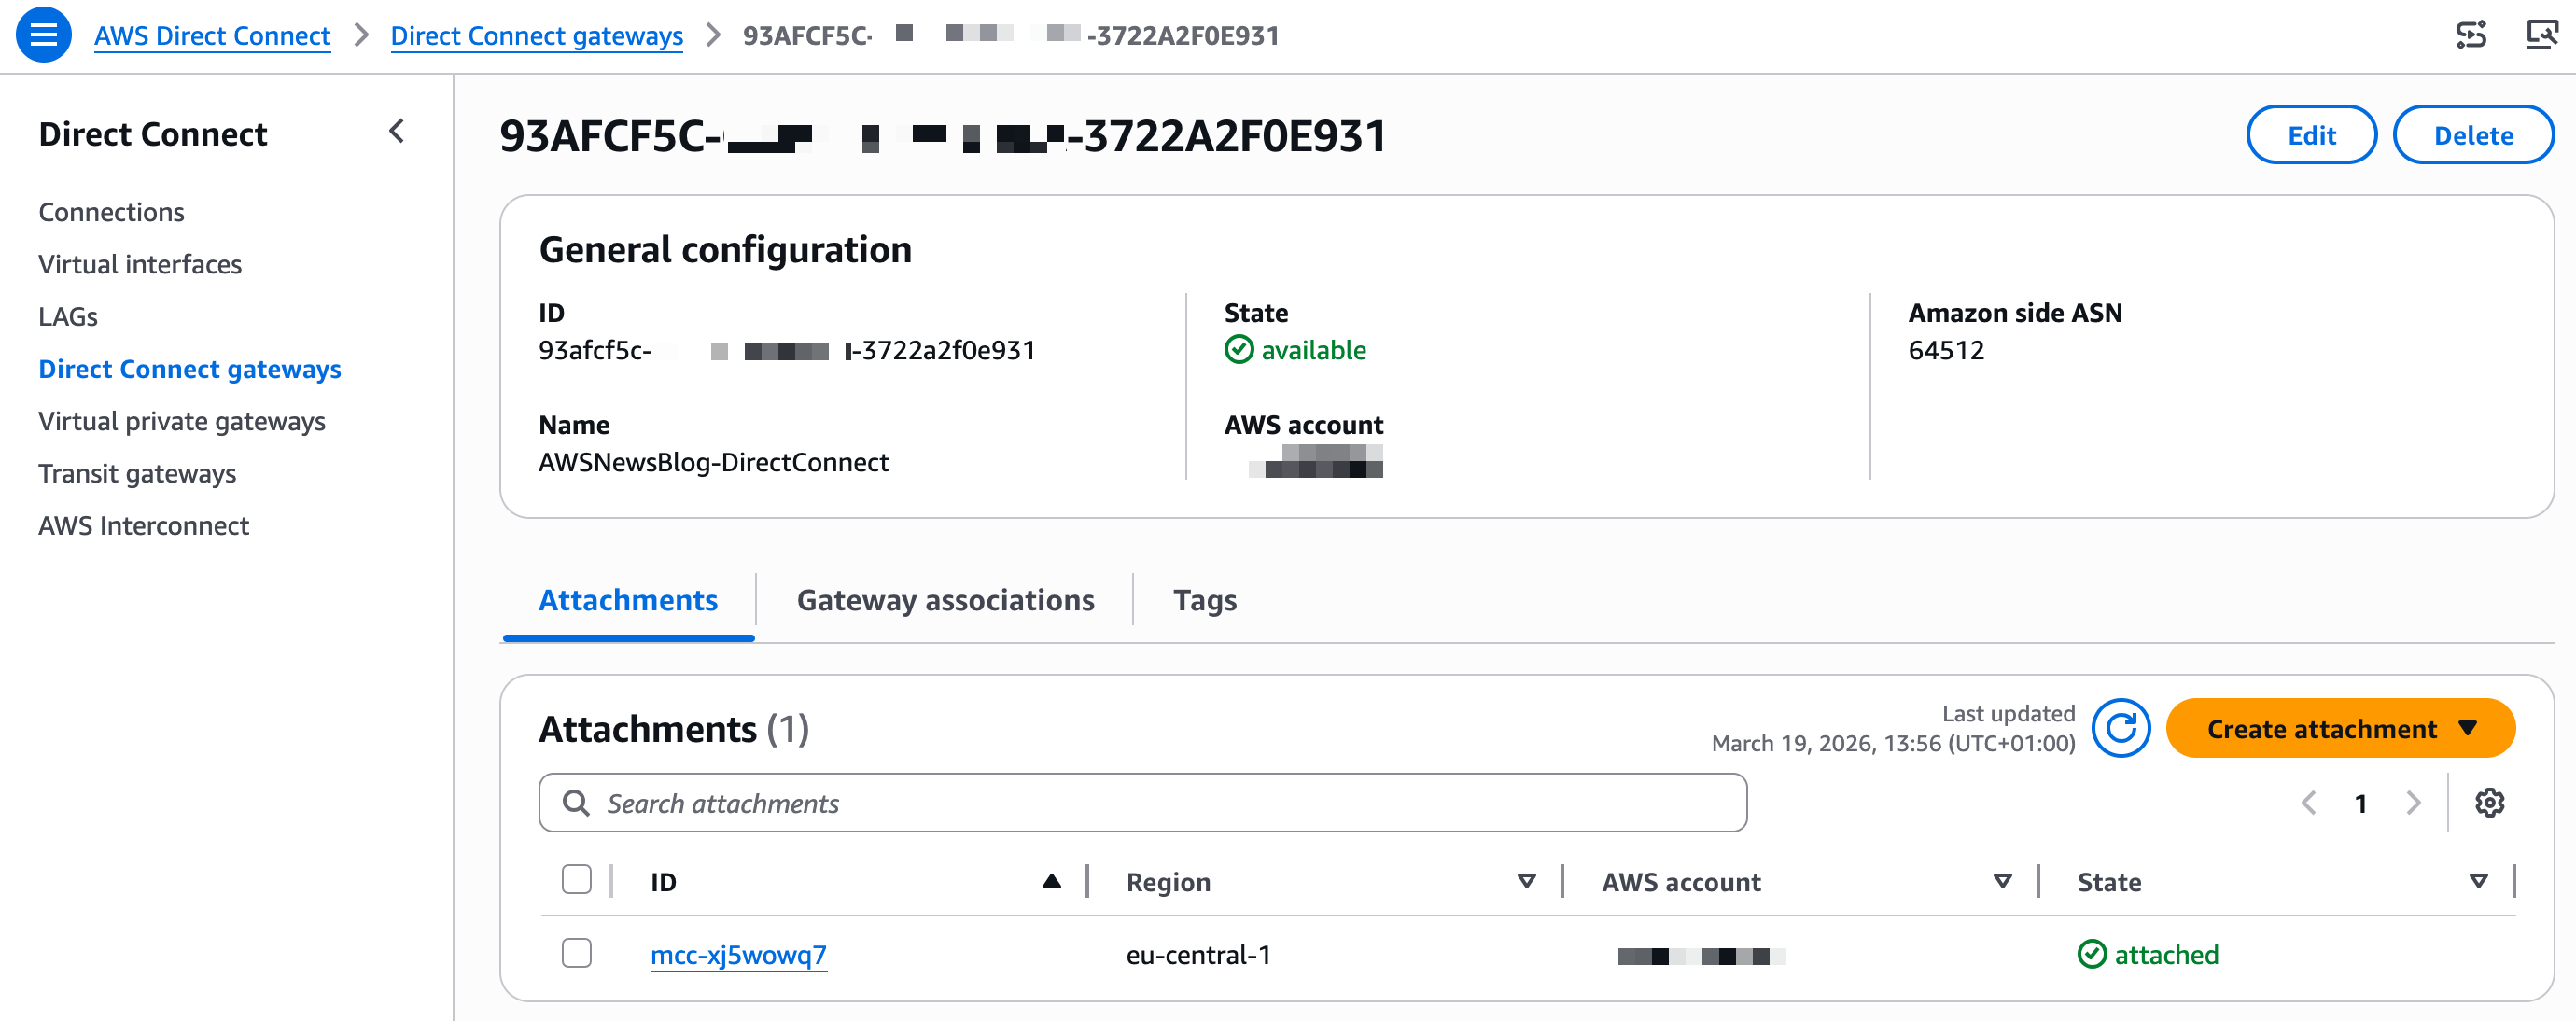
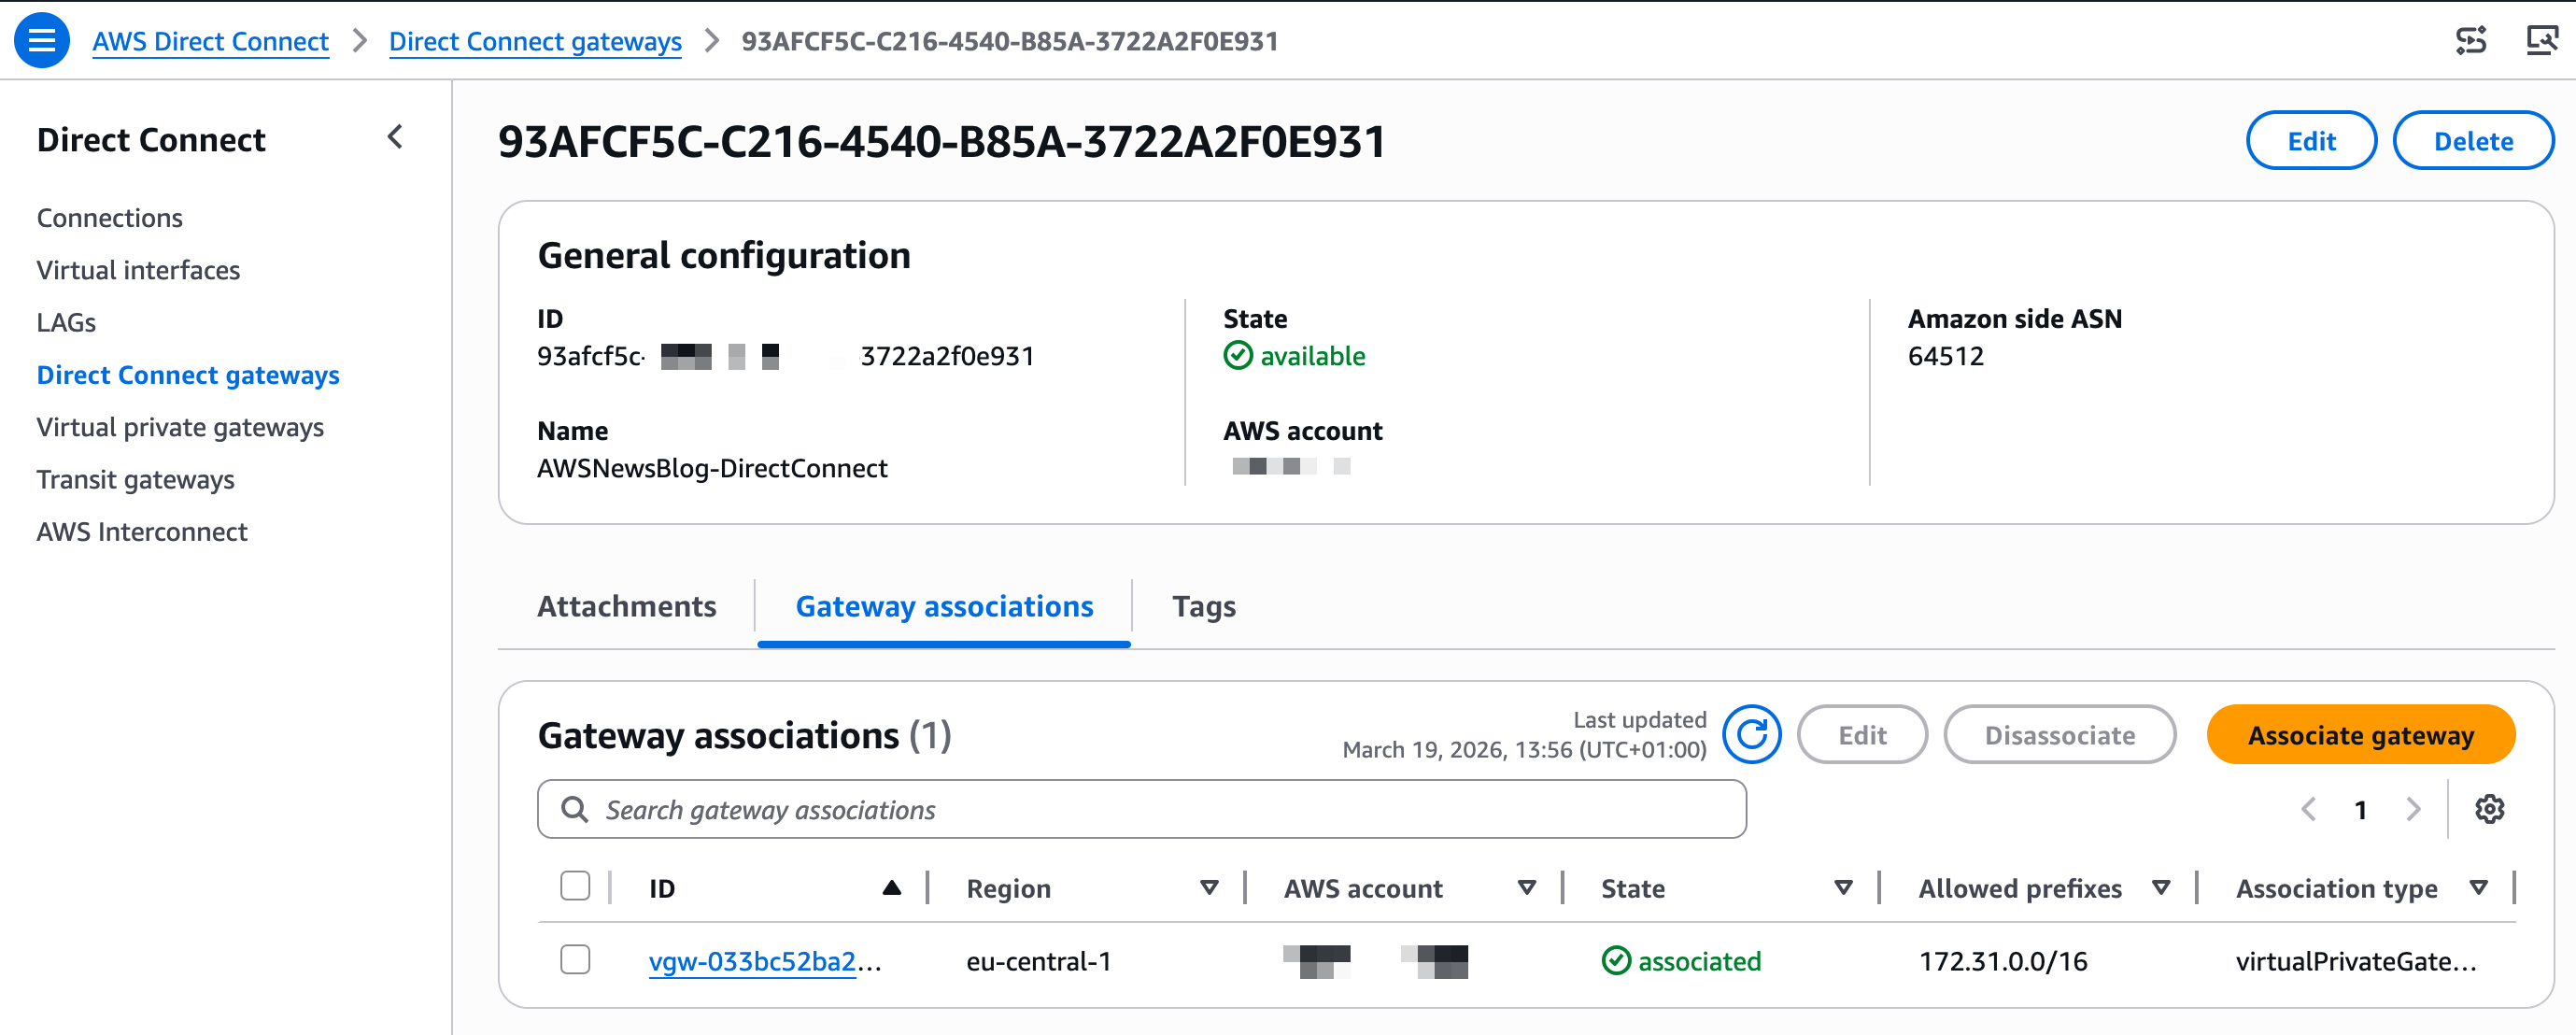
AWS Interconnect availableIn the AWS Direct Connect console, under Direct Connect gateways, I see the attachment to the new interconnect.

AWS INterconnect attachment

Step 3: associate the new gateway on the AWS side

I select Gateway associations and Associate gateway to attach the Virtual Private Gateway (VGW) that I created before starting this demo (pay attention to use a VGW in the same AWS Region as the interconnect)

AWS Interconnect associate CGW

You don’t need to configure the network routing on the GCP side. On AWS, there is a final step: add a route entry in your VPC Route tables to send all traffic to the GCP IP address range through the Virtual Gateway.

VPC Route to the VGW

Once the network setup is done. I start two compute instances, one on AWS and one on GCP.

On AWS, I verify the Security Group accepts ingress traffic on TCP:8080. I connect to the machine and I start a minimal web server:

python3 -c \
"from http.server import HTTPServer, BaseHTTPRequestHandler 
class H(BaseHTTPRequestHandler):
   def do_GET(self):
      self.send_response(200);self.end_headers()
      self.wfile.write(b'Hello AWS World!\n\n')
HTTPServer(('',8080),H).serve_forever()"

On the GCP side, I open a SSH session to the machine and I call the AWS web server by its private IP address.

AWS Interconnect : curl from GCP to AWS

Et voilà! I have a private network route between my two networks, entirely managed by the two Cloud Service Providers.

Things to know
There are a couple of configuration options that you should keep in mind:

  • When connecting networks, pay attention to the IP addresses range on both sides. The GCP and AWS VPC ranges can’t overlap. For this demo, the default range on AWS was 172.31.0.0/16and the default on GCP was 10.156.0.0/20. I was able to proceed with these default values.
  • You can configure IPV4, IPV6, or both on each side. You must select the same option on both sides.
  • The Maximum Transmission Unit (MTU) must be the same on both VPC. The default values for AWS VPCs and GCP VPCs are not. MTU is the largest packet size, in bytes, that a network interface can transmit without fragmentation. Mismatched MTU sizes between peered VPCs cause packet drops or fragmentation, leading to silent data loss, degraded throughput, and broken connections across the interconnect.
  • For more details, refer to the GCP Partner Cross Cloud Interconnect and the AWS Interconnect User Guide.

Reference architectures
When your deployment grows and you have multiple VPCs in a single region, AWS Transit Gateway gives you a centralized routing hub to connect them all through a single Interconnect attachment. You can segment traffic between environments, apply consistent routing policies, and integrate AWS Network Firewall if you need to inspect what crosses the cloud boundary.

And when you’re operating at global scale, with workloads spread across multiple AWS Regions and multiple Google Cloud environments, AWS Cloud WAN extends that same model across the world. Any region in your network can reach any Interconnect attachment globally, with centralized policy management and segment-based routing that applies consistently everywhere you operate.

My colleagues Alexandra and Santiago documented these reference architectures in their blog post: Build resilient and scalable multicloud connectivity architectures with AWS Interconnect – multicloud.

AWS Interconnect – last mile
Based on the same architecture and design as AWS Interconnect – multicloud, AWS Interconnect – last mile provides the ability to connect your on-premises or remote location to AWS through a participating network provider’s last-mile infrastructure, directly from the AWS Management Console.

The onboarding process mirrors AWS Interconnect – multicloud: you select a provider, authenticate, and specify your connection endpoints and bandwidth. AWS generates an activation key that you provide in the provider console to complete the configuration. AWS Interconnect – last mile automatically provisions four redundant connections across two physical locations, configures BGP routing, and activates MACsec encryption and Jumbo Frames by default. The result is a resilient private connection to AWS that aligns with best practices, without requiring you to manually configure networking components.

AWS Interconnect - lastmile

AWS Interconnect – last mile supports bandwidths from 1 Gbps to 100 Gbps, and you can adjust bandwidth from the console without reprovisioning. The service includes a 99.99% availability SLA up to the Direct Connect port and bundles CloudWatch Network Synthetic Monitor for connection health monitoring. Just like AWS Interconnect – multicloud, AWS Interconnect – last mile attaches to a Direct Connect Gateway, which connects to your Virtual Private Gateway, Transit Gateway, or AWS Cloud WAN deployment. For more details, refer to the AWS Interconnect User Guide.

Scott Yow, SVP Product at Lumen Technologies, wrote:

By combining AWS Interconnect – last mile with Lumen fiber network and Cloud Interconnect, we simplify the last-mile complexity that often slows cloud adoption and enable a faster, and more resilient path to AWS for customers.

Pricing and availability
AWS Interconnect – multicloud and AWS Interconnect – last mile pricing is based on a flat hourly rate for the capacity you request, billed prorata by the hour. You select the bandwidth tier that fits your workload needs.

AWS Interconnect – multicloud pricing varies by region pair: a connection between US East (N. Virginia) and Google Cloud N. Virginia is priced differently from a connection between US East (N. Virginia) and a more distant region. When you use AWS Cloud WAN, the global any-to-any routing model means traffic can traverse multiple regions, which affects the total cost of your deployment. I recommend reviewing the AWS Interconnect pricing page for the full rate card by region pair and capacity tier before sizing your connection.

AWS Interconnect – multicloud is available today in five region pairs: US East (N. Virginia) to Google Cloud N. Virginia, US West (N. California) to Google Cloud Los Angeles, US West (Oregon) to Google Cloud Oregon, Europe (London) to Google Cloud London, and Europe (Frankfurt) to Google Cloud Frankfurt. Microsoft Azure support is coming later in 2026.

AWS Interconnect – last mile is launching in US East (N. Virginia) with Lumen as the initial partner. Additional partners, including AT&T and Megaport, are in progress, and additional regions are planned.

To get started with AWS Interconnect, visit the AWS Direct Connect console and select AWS Interconnect from the navigation menu.

I’d love to hear how you’re using AWS Interconnect in your environment. Leave a comment below or reach out through the AWS re:Post community.

— seb

Launching S3 Files, making S3 buckets accessible as file systems

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/launching-s3-files-making-s3-buckets-accessible-as-file-systems/

I’m excited to announce Amazon S3 Files, a new file system that seamlessly connects any AWS compute resource with Amazon Simple Storage Service (Amazon S3).

More than a decade ago, as an AWS trainer, I spent countless hours explaining the fundamental differences between object storage and file systems. My favorite analogy was comparing S3 objects to books in a library (you can’t edit a page, you need to replace the whole book) versus files on your computer that you can modify page by page. I drew diagrams, created metaphors, and helped customers understand why they needed different storage types for different workloads. Well, today that distinction becomes a bit more flexible.

With S3 Files, Amazon S3 is the first and only cloud object store that offers fully-featured, high-performance file system access to your data. It makes your buckets accessible as file systems. This means changes to data on the file system are automatically reflected in the S3 bucket and you have fine-grained control over synchronization. S3 Files can be attached to multiple compute resources enabling data sharing across clusters without duplication.

Until now, you had to choose between Amazon S3 cost, durability, and the services that can natively consume data from it or a file system’s interactive capabilities. S3 Files eliminates that tradeoff. S3 becomes the central hub for all your organization’s data. It’s accessible directly from any AWS compute instance, container, or function, whether you’re running production applications, training ML models, or building agentic AI systems.

You can access any general purpose bucket as a native file system on your Amazon Elastic Compute Cloud (Amazon EC2) instances, containers running on Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS), or AWS Lambda functions. The file system presents S3 objects as files and directories, supporting all Network File System (NFS) v4.1+ operations like creating, reading, updating, and deleting files.

As you work with specific files and directories through the file system, associated file metadata and contents are placed onto the file system’s high-performance storage. By default, files that benefit from low-latency access are stored and served from the high performance storage. For files not stored on high performance storage such as those needing large sequential reads, S3 Files automatically serves those files directly from Amazon S3 to maximize throughput. For byte-range reads, only the requested bytes are transferred, minimizing data movement and costs.

The system also supports intelligent pre-fetching to anticipate your data access needs. You also have fine-grained control over what gets stored on the file system’s high performance storage. You can decide whether to load full file data or metadata only, which means you can optimize for your specific access patterns.

Under the hood, S3 Files uses Amazon Elastic File System (Amazon EFS) and delivers ~1ms latencies for active data. The file system supports concurrent access from multiple compute resources with NFS close-to-open consistency, making it ideal for interactive, shared workloads that mutate data, from agentic AI agents collaborating through file-based tools to ML training pipelines processing datasets.

Let me show you how to get started.
Creating my first Amazon S3 file system, mounting, and using it from an EC2 instance is straightforward.

I have an EC2 instance and a general purpose bucket. In this demo, I configure an S3 file system and access the bucket from an EC2 instance, using regular file system commands.

For this demo, I use the AWS Management Console. You can also use the AWS Command Line Interface (AWS CLI) or infrastructure as code (IaC).

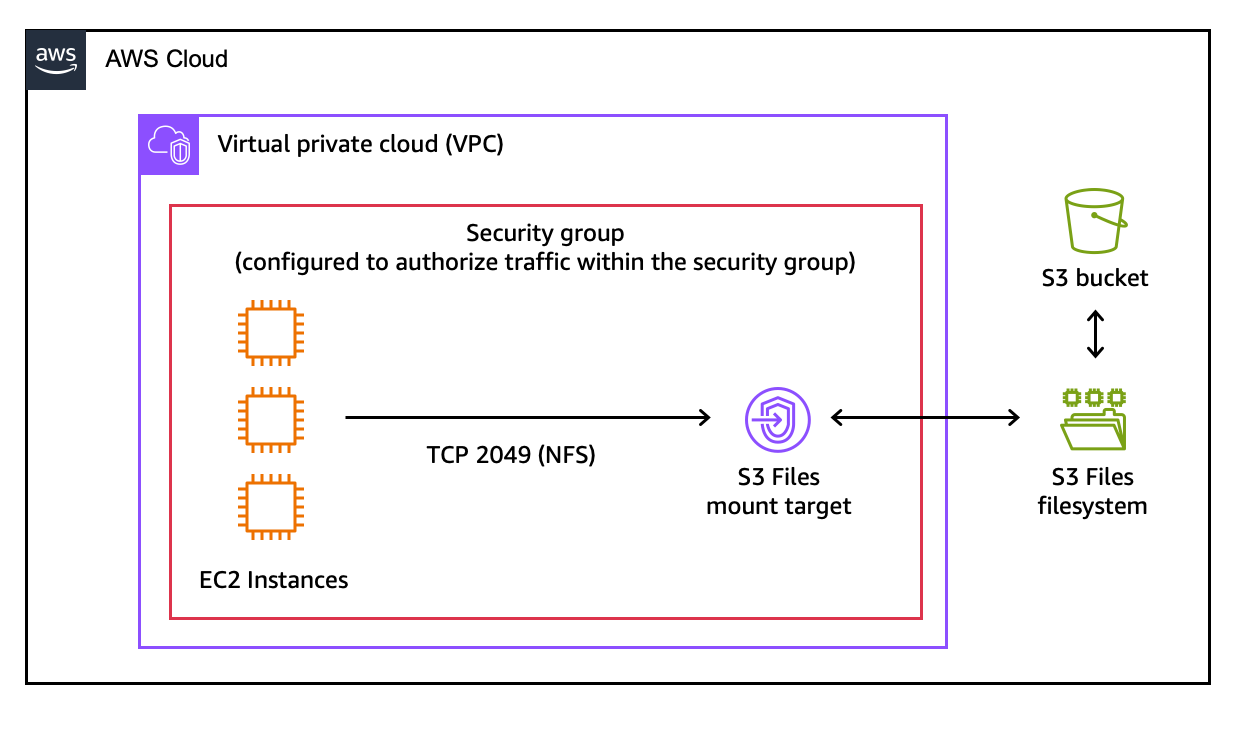
Here is the architecture diagram for this demo.

S3 Files demo architectureStep 1: Create an S3 file system.

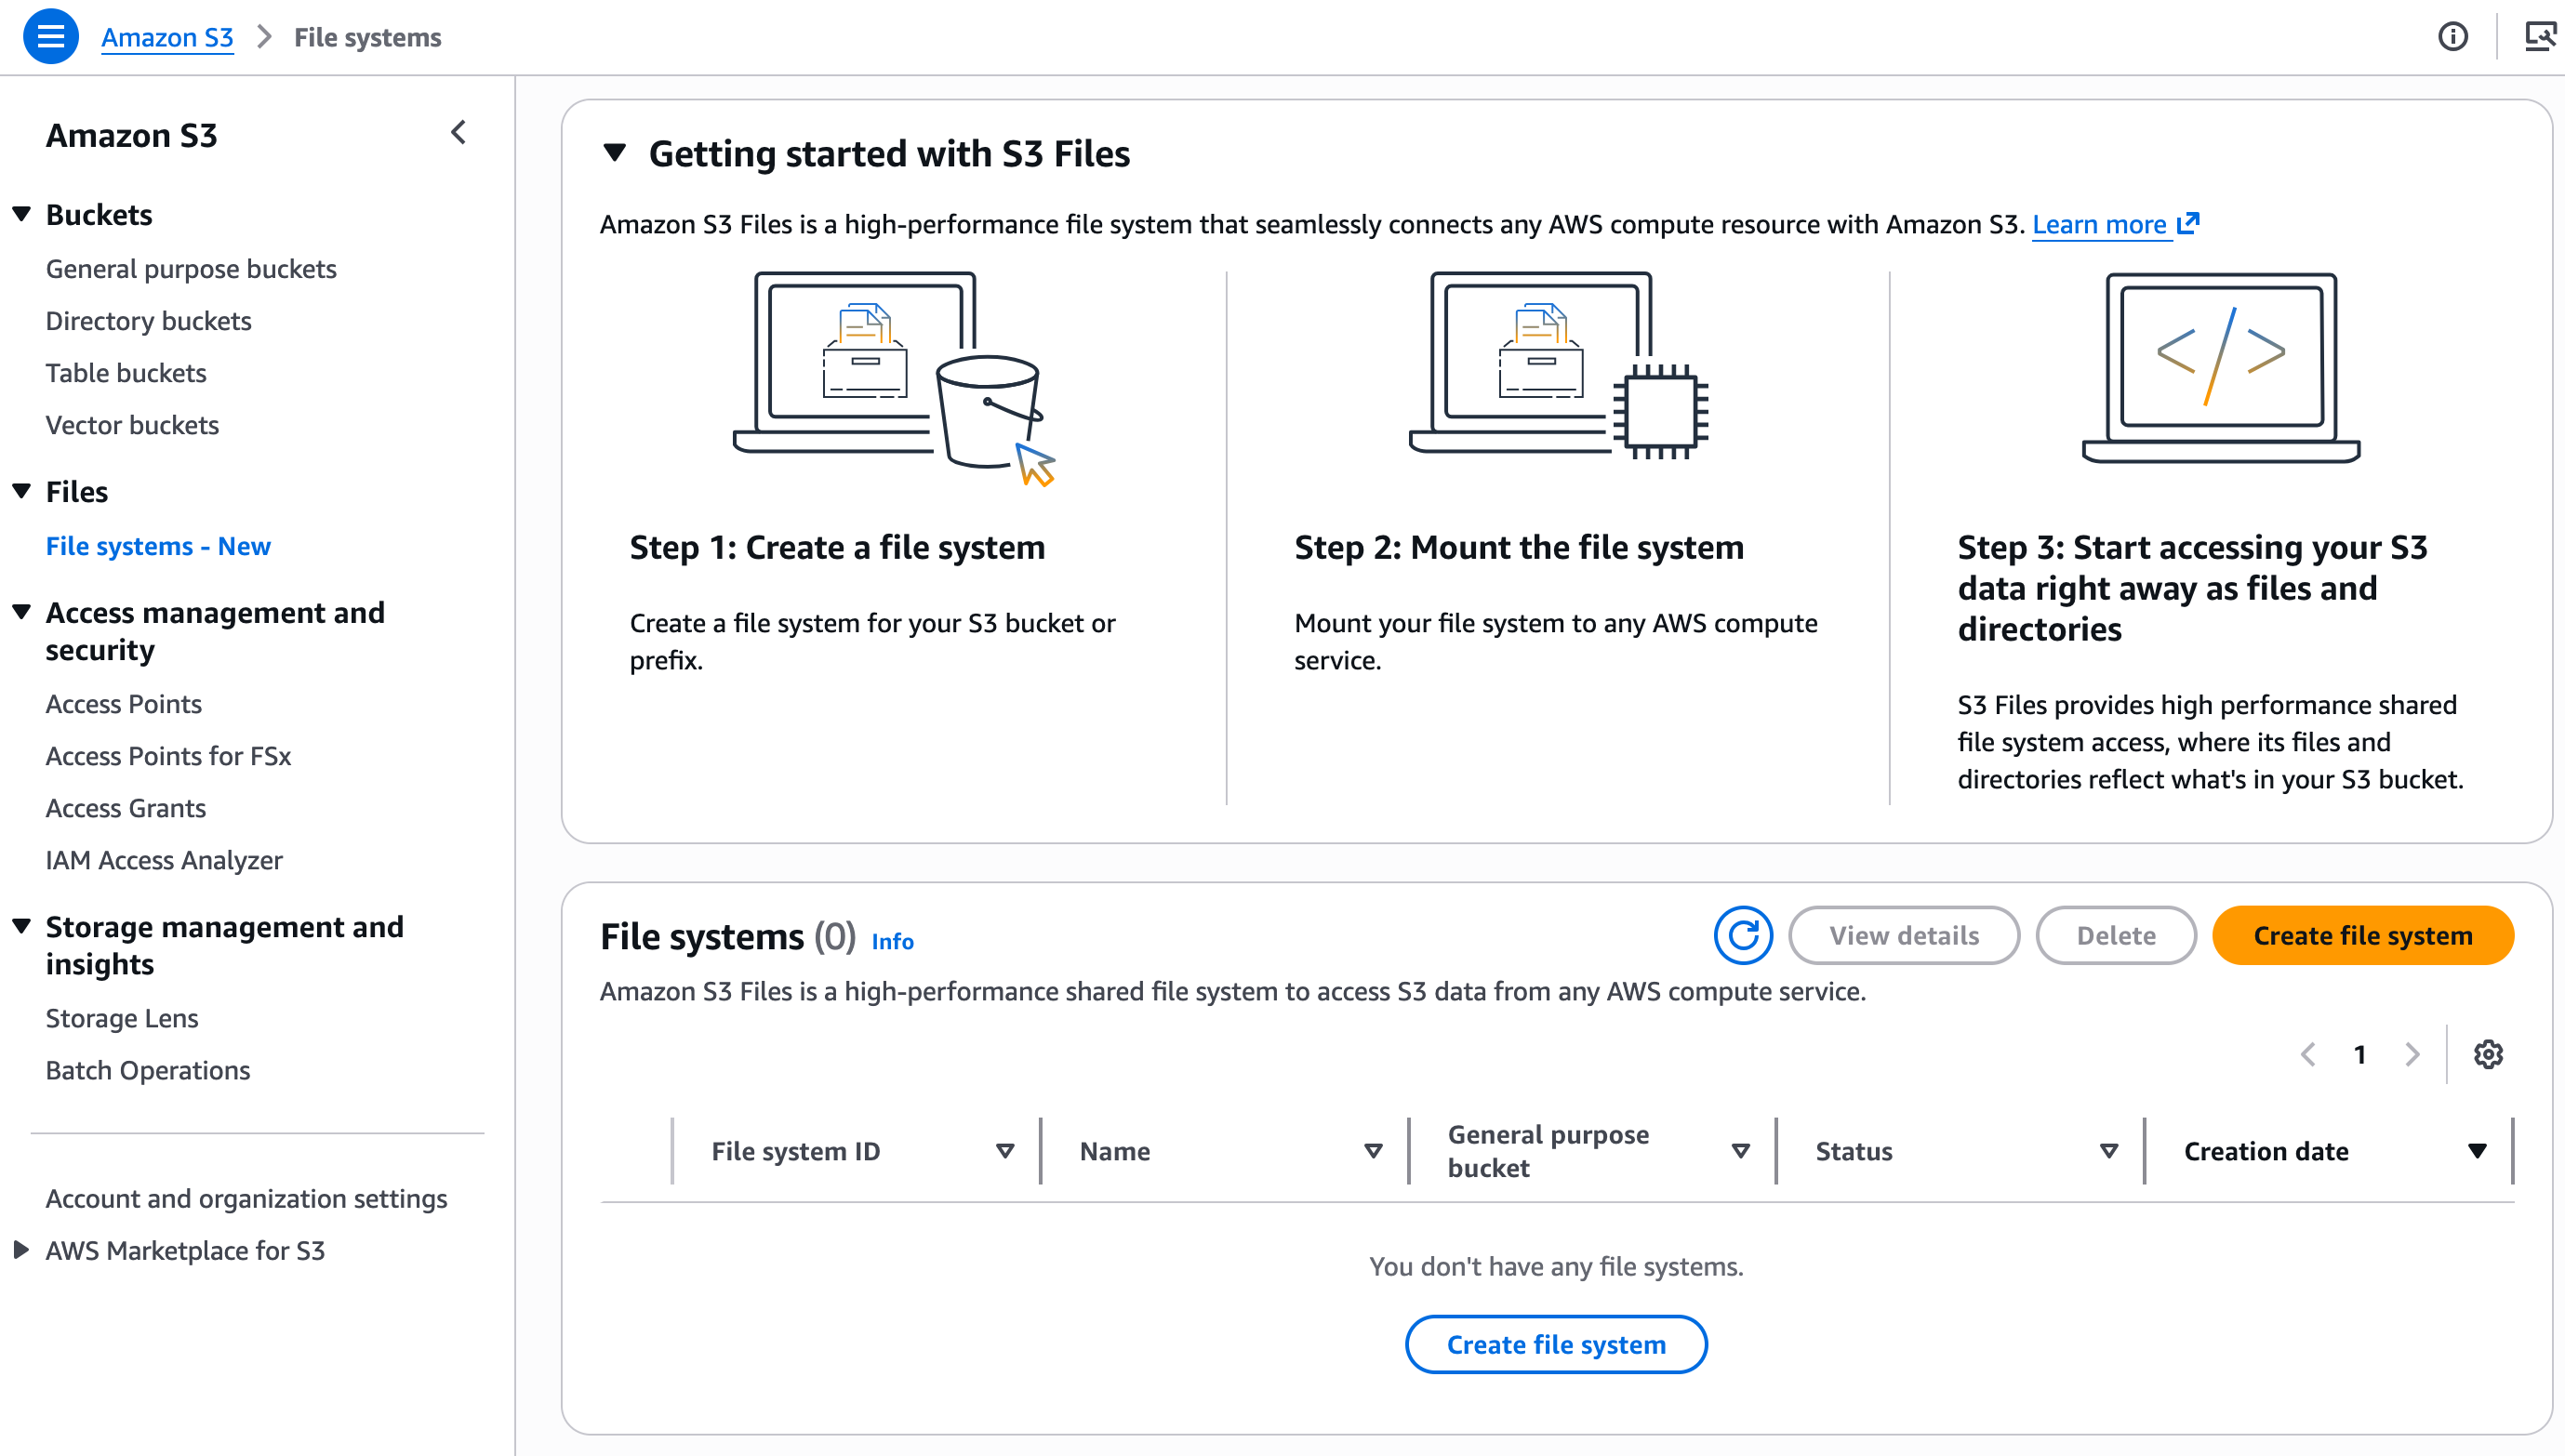
On the Amazon S3 section of the console, I choose File systems and then Create file system.

S3 Files create file system

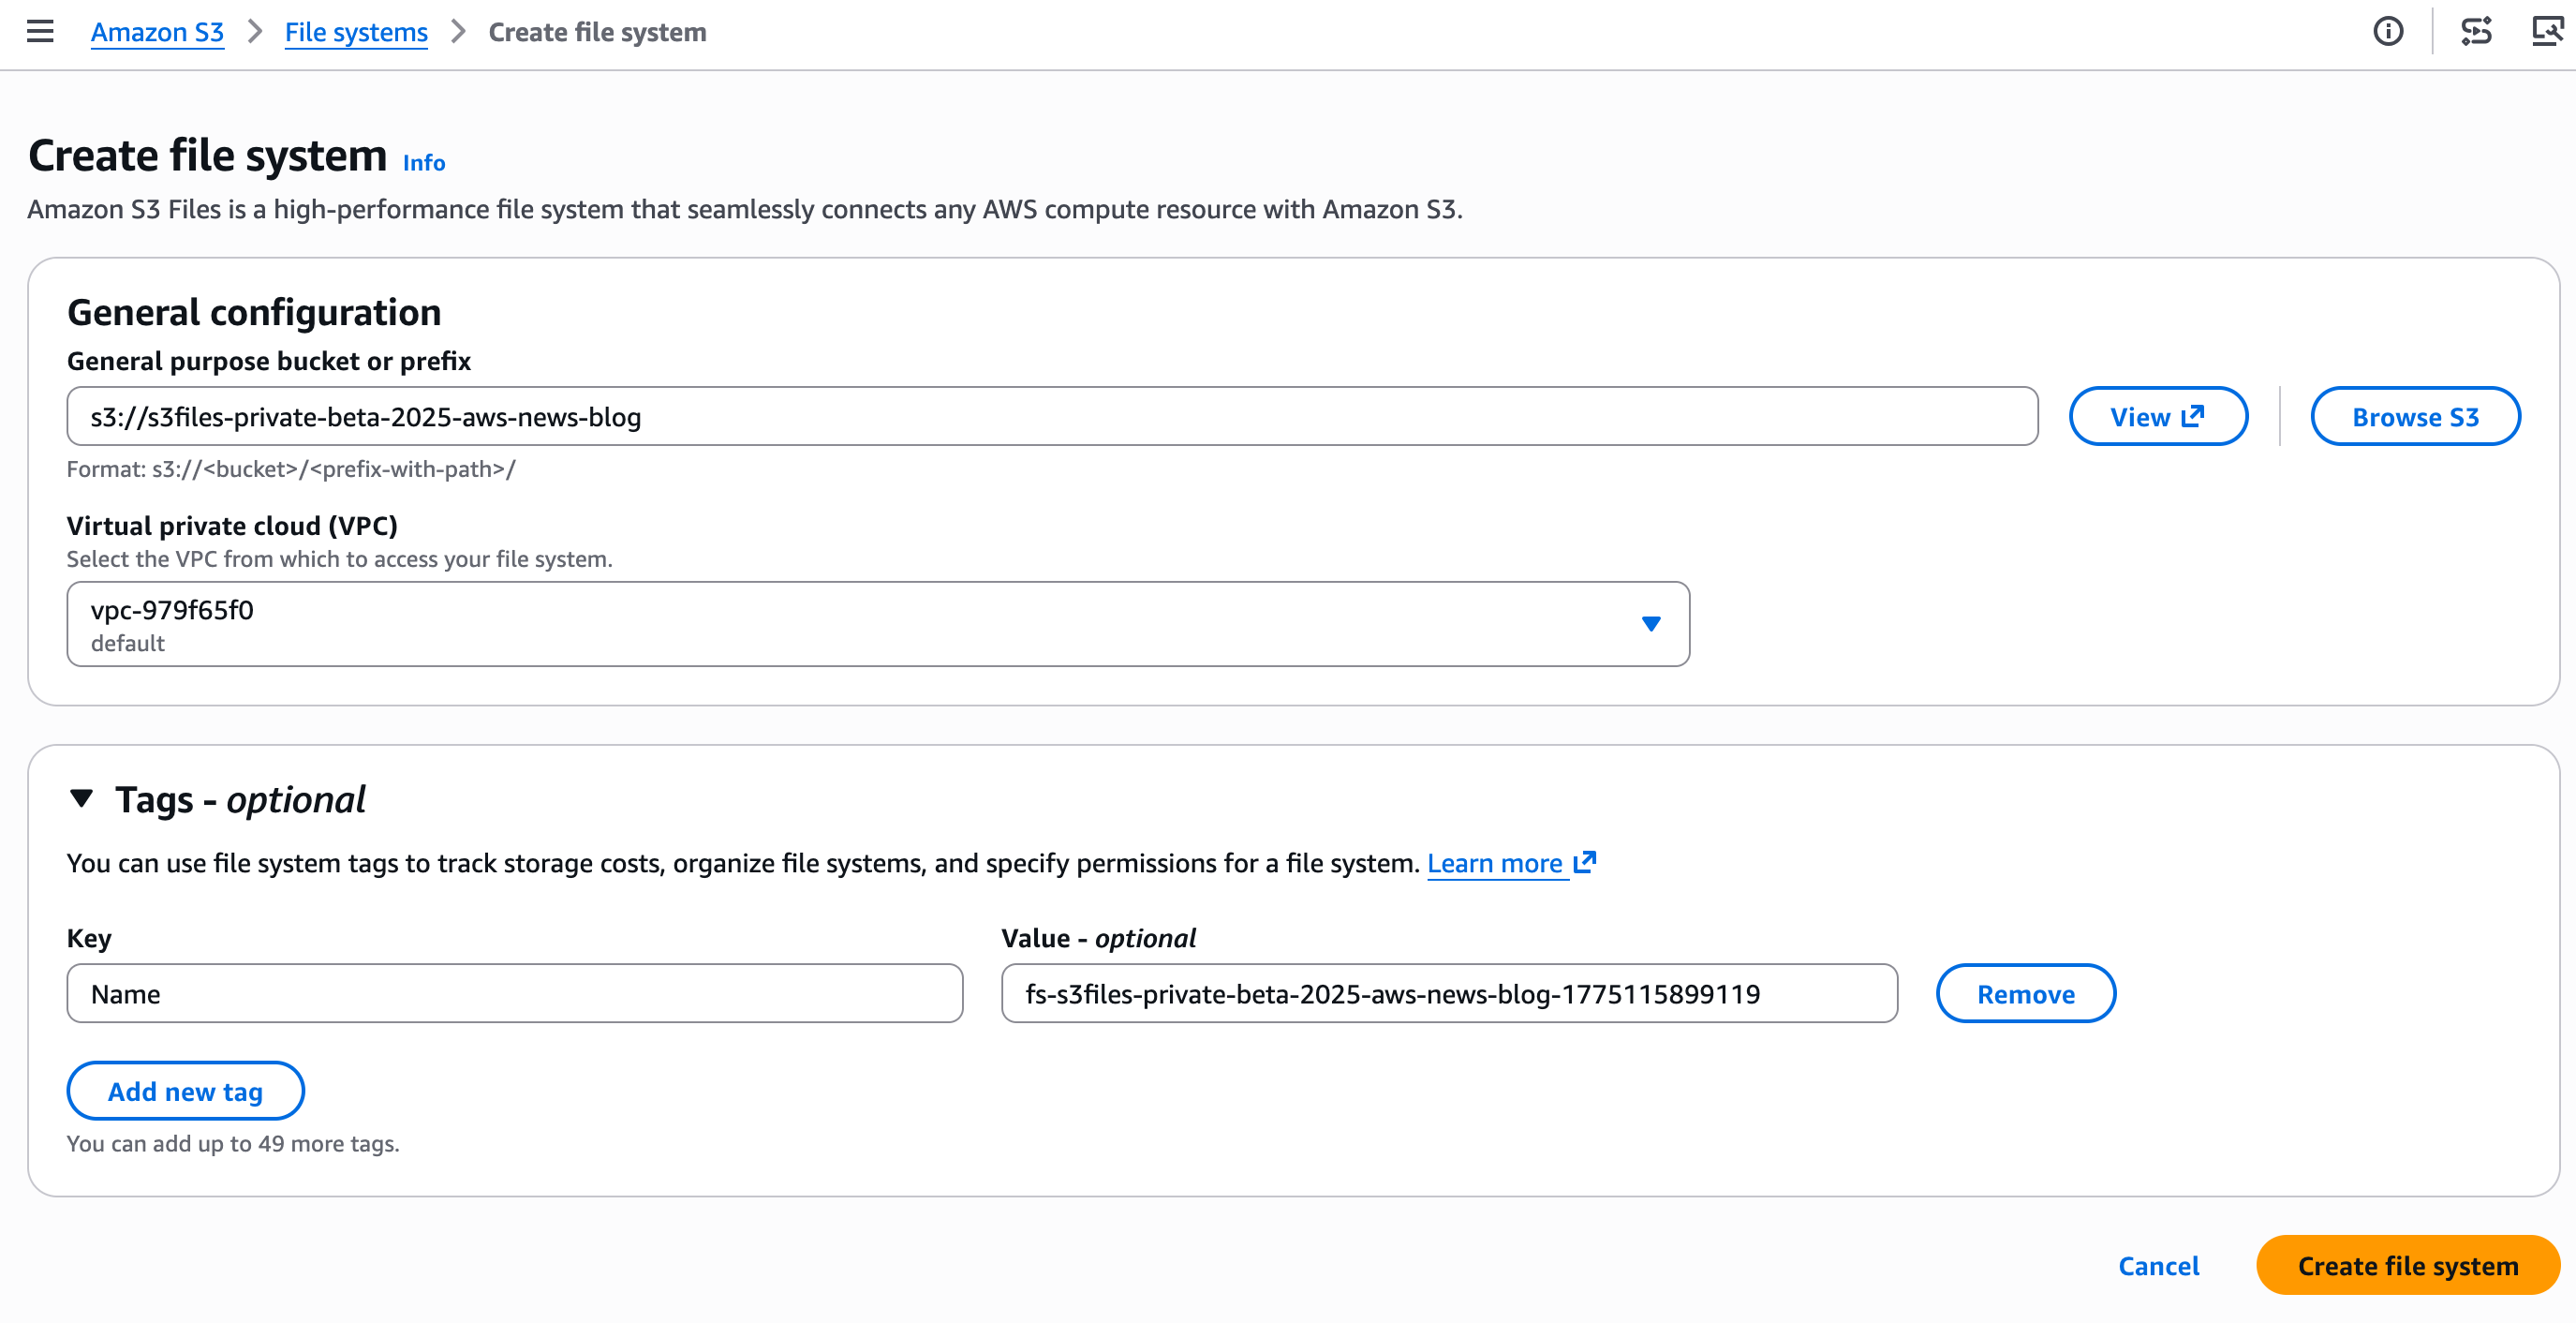
I enter the name of the bucket I want to expose as a file system and choose Create file system.

S3 Files create file system, part 2

Step 2: Discover the mount target.

A mount target is a network endpoint that will live in my virtual private cloud (VPC). It allows my EC2 instance to access the S3 file system.

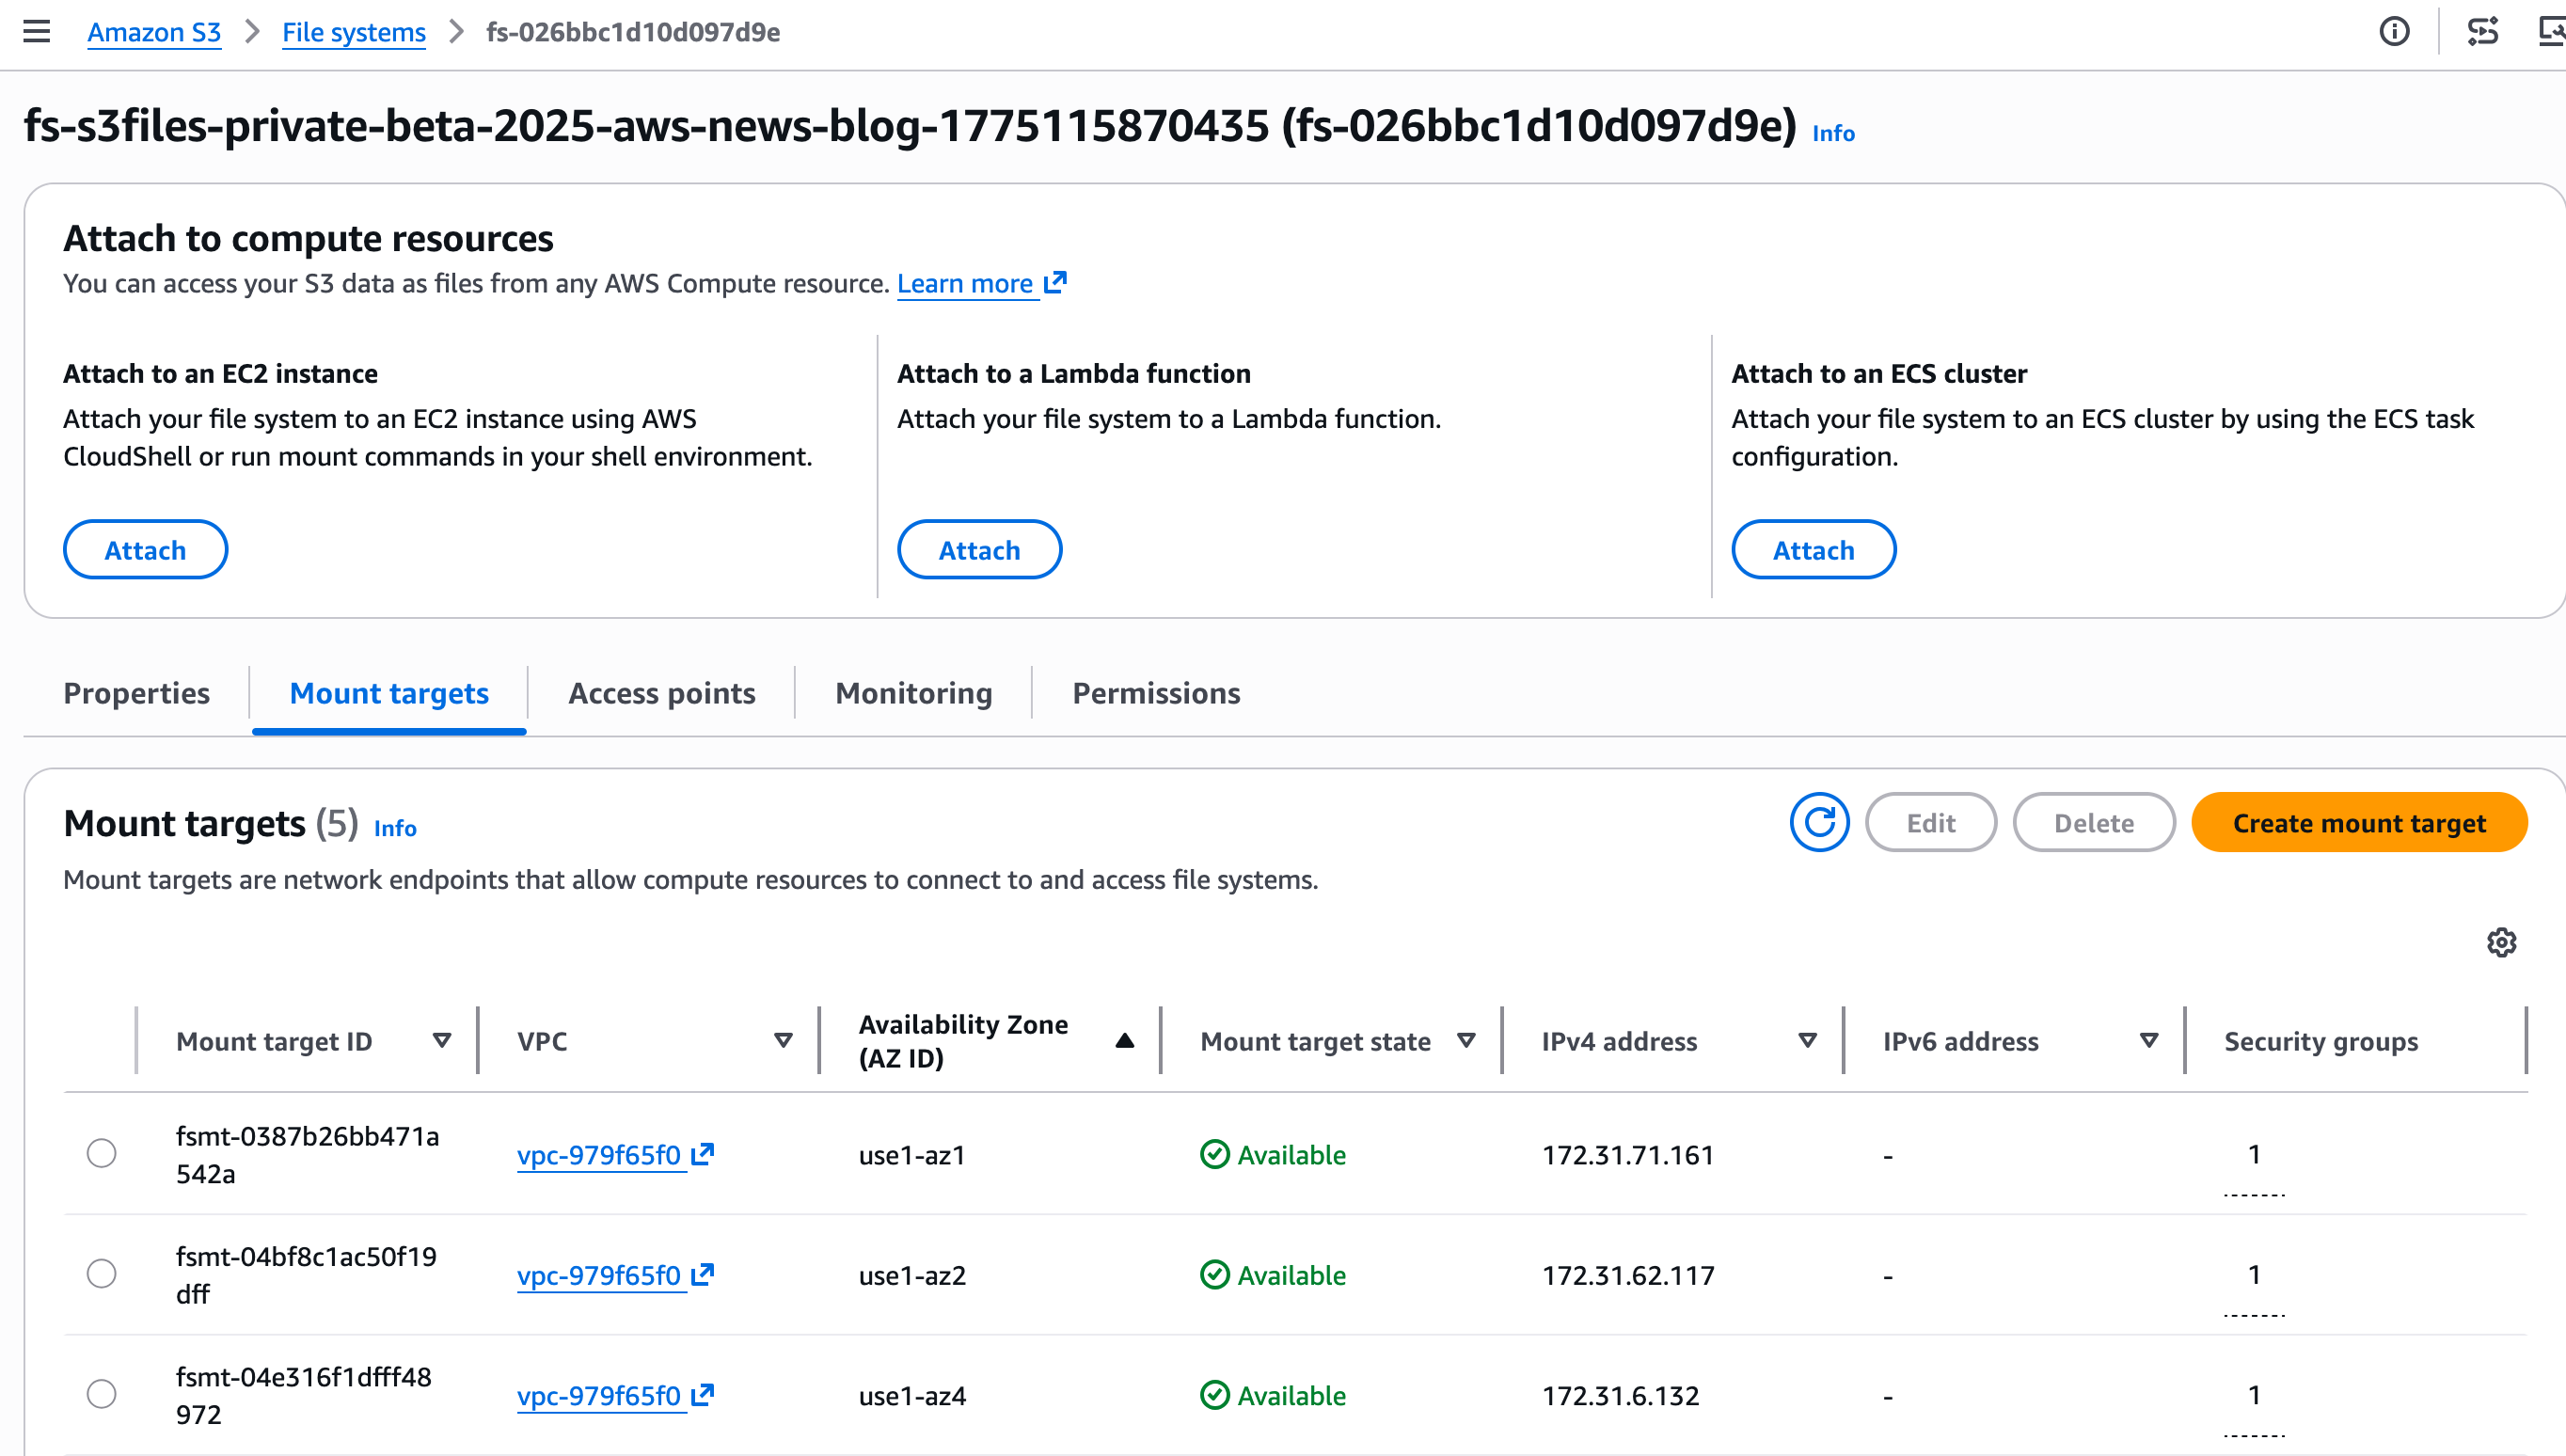
The console creates the mount targets automatically. I take notes of the Mount target IDs on the Mount targets tab.

When using the CLI, two separate commands are necessary to create the file system and its mount targets. First, I create the S3 file system with create-file-system. Then, I create the mount target with create-mount target.

Step 3: Mount the file system on my EC2 instance.

After it’s connected to an EC2 instance, I type:

sudo mkdir /home/ec2-user/s3files sudo mount -t s3files fs-0aa860d05df9afdfe:/ /home/ec2-user/s3files

I can now work with my S3 data directly through the mounted file system in ~/s3files, using standard file operations.

When I make updates to my files in the file system, S3 automatically manages and exports all updates as a new object or a new version on an existing object back in my S3 bucket within minutes.

Changes made to objects on the S3 bucket are visible in the file system within a few seconds but can sometimes take a minute or longer.

# Create a file on the EC2 file system 
echo "Hello S3 Files" > s3files/hello.txt 

# and verify it's here 
ls -al s3files/hello.txt
 -rw-r--r--. 1 ec2-user ec2-user 15 Oct 22 13:03 s3files/hello.txt 

# See? the file is also on S3 
aws s3 ls s3://s3files-aws-news-blog/hello.txt 
2025-10-22 13:04:04 15 hello.txt 

# And the content is identical! 
aws s3 cp s3://s3files-aws-news-blog/hello.txt . && cat hello.txt
Hello S3 Files

Things to know
Let me share some important technical details that I think you’ll find useful.

Another question I frequently hear in customer conversations is about choosing the right file service for your workloads. Yes, I know what you’re thinking: AWS and its seemingly overlapping services, keeping cloud architects entertained during their architecture review meetings. Let me help demystify this one.

S3 Files works best when you need interactive, shared access to data that lives in Amazon S3 through a high performance file system interface. It’s ideal for workloads where multiple compute resources—whether production applications, agentic AI agents using Python libraries and CLI tools, or machine learning (ML) training pipelines—need to read, write, and mutate data collaboratively. You get shared access across compute clusters without data duplication, sub-millisecond latency, and automatic synchronization with your S3 bucket.

For workloads migrating from on-premises NAS environments, Amazon FSx provides the familiar features and compatibility you need. Amazon FSx is also ideal for high-performance computing (HPC) and GPU cluster storage with Amazon FSx for Lustre. It’s particularly valuable when your applications require specific file system capabilities from Amazon FSx for NetApp ONTAP, Amazon FSx for OpenZFS, or Amazon FSx for Windows File Server.

Pricing and availability
S3 Files is available today in all commercial AWS Regions.

You pay for the portion of data stored in your S3 file system, for small file read and all write operations to the file system, and for S3 requests during data synchronization between the file system and the S3 bucket. The Amazon S3 pricing page has all the details.

From discussions with customers, I believe S3 Files helps simplify cloud architectures by eliminating data silos, synchronization complexity, and manual data movement between objects and files. Whether you’re running production tools that already work with file systems, building agentic AI systems that rely on file-based Python libraries and shell scripts, or preparing datasets for ML training, S3 Files lets these interactive, shared, hierarchical workloads access S3 data directly without choosing between the durability of Amazon S3 and cost benefits and a file system’s interactive capabilities. You can now use Amazon S3 as the place for all your organizations’ data, knowing the data is accessible directly from any AWS compute instance, container, and function.

To learn more and get started, visit the S3 Files documentation.

I’d love to hear how you use this new capability. Feel free to share your feedback in the comments below.

— seb

Announcing the AWS Sustainability console: Programmatic access, configurable CSV reports, and Scope 1–3 reporting in one place

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/announcing-the-aws-sustainability-console-programmatic-access-configurable-csv-reports-and-scope-1-3-reporting-in-one-place/

As many of you are, I’m a parent. And like you, I think about the world I’m building for my children. That’s part of why today’s launch matters for many of us. I’m excited to announce the launch of the AWS Sustainability console, a standalone service that consolidates all AWS sustainability reporting and resources in one place.

With the The Climate Pledge, Amazon set a goal in 2019 to reach net-zero carbon across our operations by 2040. That commitment shapes how AWS builds its data centers and services. In addition, AWS is also committed to helping you measure and reduce the environmental footprint of your own workloads. The AWS Sustainability console is the latest step in that direction.

The AWS Sustainability console builds on the Customer Carbon Footprint Tool (CCFT), which lives inside the AWS Billing console, and introduces a new set of capabilities for which you’ve been asking.

Until now, accessing your carbon footprint data required billing-level permissions. That created a practical problem: sustainability professionals and reporting teams often don’t have (and shouldn’t need) access to cost and billing data. Getting the right people access to the right data meant navigating permission structures that weren’t designed with sustainability workflows in mind. The AWS Sustainability console has its own permissions model, independent of the Billing console. Sustainability professionals can now get direct access to emissions data without requiring billing permissions to be granted alongside it.

The console includes Scope 1, 2, and 3 emissions attributed to your AWS usage and shows you a breakdown by AWS Region, service, such as Amazon CloudFront, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Storage Service (Amazon S3). The underlying data and methodology haven’t changed with this launch; these are the same as the ones used by the CCFT. We changed how you can access and work with the data.

As sustainability reporting requirements have grown more complex, teams need more flexibility accessing and working with their emissions data. The console now includes a Reports page where you can download preset monthly and annual carbon emissions reports covering both market-based method (MBM) and location-based method (LBM) data. You can also build a custom comma-separated values (CSV) report by selecting which fields to include, the time granularity, and other filters.

If your organization’s fiscal year doesn’t align with the calendar year, you can now configure the console to match your reporting period. When that is set, all data views and exports reflect your fiscal year and quarters, which removes a common friction point for finance and sustainability teams working in parallel.

You can also use the new API or the AWS SDKs to integrate emissions data into your own reporting pipelines, dashboards, or compliance workflows. This is useful for teams that need to pull data for a specific month across a large number of accounts without setting up a data export or for organizations that need to establish custom account groupings that don’t align with their existing AWS Organizations structure.

You can read about the latest features released and methodology updates directly on the Release notes page on the Learn more tab.

Lets see it in action
To show you the Sustainability console, I opened the AWS Management Console and searched for “sustainability” in the search bar at the top of the screen.

Sustainability console - carbon emission 1

Sustainability console - carbon emission 2

The Carbon emissions section gives an estimate on your carbon emissions, expressed in metric tons of carbon dioxide equivalent (MTCO2e). It shows the emissions by scope, expressed in the MBM and the LBM. On the right side of the screen, you can adjust the date range or filter by service, Regions, and more.

For those unfamiliar: Scope 1 includes direct emissions from owned or controlled sources (for example, data center fuel use); Scope 2 covers indirect emissions from the production of purchased energy (with MBM accounting for energy attribute certificates and LBM using average local grid emissions); and Scope 3 includes other indirect emissions across the value chain, such as server manufacturing and data center construction. You can read more about this in our methodology document, which was independently verified by Apex, a third-party consultant.

I can also use API or AWS Command Line Interface (AWS CLI) to programmatically pull the emissions data.

aws sustainability get-estimated-carbon-emissions \
     --time-period='{"Start":"2025-03-01T00:00:00Z","End":"2026-03-01T23:59:59.999Z"}'

{
    "Results": [
        {
            "TimePeriod": {
                "Start": "2025-03-01T00:00:00+00:00",
                "End": "2025-04-01T00:00:00+00:00"
            },
            "DimensionsValues": {},
            "ModelVersion": "v3.0.0",
            "EmissionsValues": {
                "TOTAL_LBM_CARBON_EMISSIONS": {
                    "Value": 0.7,
                    "Unit": "MTCO2e"
                },
                "TOTAL_MBM_CARBON_EMISSIONS": {
                    "Value": 0.1,
                    "Unit": "MTCO2e"
                }
            }
        },
...

The combination of the visual console and the new API gives you two additional ways to work with your data, in addition to the Data Exports still available. You can now explore and identify hotspots on the console and automate the reporting you want to share with stakeholders.

The Sustainability console is designed to grow. We plan to continue to release new features as we grow the console’s capabilities alongside our customers.

Get started today
The AWS Sustainability console is available today at no additional cost. You can access it from the AWS Management Console. Historical data is available going back to January 2022, so you can start exploring your emissions trends right away.

Get started on the console today. If you want to learn more about the AWS commitment to sustainability, visit the AWS Sustainability page.

— seb

Twenty years of Amazon S3 and building what’s next

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/twenty-years-of-amazon-s3-and-building-whats-next/

Twenty years ago today, on March 14, 2006, Amazon Simple Storage Service (Amazon S3) quietly launched with a modest one-paragraph announcement on the What’s New page:

Amazon S3 is storage for the Internet. It is designed to make web-scale computing easier for developers. Amazon S3 provides a simple web services interface that can be used to store and retrieve any amount of data, at any time, from anywhere on the web. It gives any developer access to the same highly scalable, reliable, fast, inexpensive data storage infrastructure that Amazon uses to run its own global network of web sites.

Even Jeff Barr’s blog post was only a few paragraphs, written before catching a plane to a developer event in California. No code examples. No demo. Very low fanfare. Nobody knew at the time that this launch would shape our entire industry.

The early days: Building blocks that just work
At its core, S3 introduced two straightforward primitives: PUT to store an object and GET to retrieve it later. But the real innovation was the philosophy behind it: create building blocks that handle the undifferentiated heavy lifting, which freed developers to focus on higher-level work.

From day one, S3 was guided by five fundamentals that remain unchanged today.

Security means your data is protected by default. Durability is designed for 11 nines (99.999999999%), and we operate S3 to be lossless. Availability is designed into every layer, with the assumption that failure is always present and must be handled. Performance is optimized to store virtually any amount of data without degradation. Elasticity means the system automatically grows and shrinks as you add and remove data, with no manual intervention required.

When we get these things right, the service becomes so straightforward that most of you never have to think about how complex these concepts are.

S3 today: Scale beyond imagination
Throughout 20 years, S3 has remained committed to its core fundamentals even as it’s grown to a scale that’s hard to comprehend.

When S3 first launched, it offered approximately one petabyte of total storage capacity across about 400 storage nodes in 15 racks spanning three data centers, with 15 Gbps of total bandwidth. We designed the system to store tens of billions of objects, with a maximum object size of 5 GB. The initial price was 15 cents per gigabyte.

S3 key metrics illustration

Today, S3 stores more than 500 trillion objects and serves more than 200 million requests per second globally across hundreds of exabytes of data in 123 Availability Zones in 39 AWS Regions, for millions of customers. The maximum object size has grown from 5 GB to 50 TB, a 10,000 fold increase. If you stacked all of the tens of millions S3 hard drives on top of each other, they would reach the International Space Station and almost back.

Even as S3 has grown to support this incredible scale, the price you pay has dropped. Today, AWS charges slightly over 2 cents per gigabyte. That’s a price reduction of approximately 85% since launch in 2006. In parallel, we’ve continued to introduce ways to further optimize storage spend with storage tiers. For example, our customers have collectively saved more than $6 billion in storage costs by using Amazon S3 Intelligent-Tiering as compared to Amazon S3 Standard.

Over the past two decades, the S3 API has been adopted and used as a reference point across the storage industry. Multiple vendors now offer S3 compatible storage tools and systems, implementing the same API patterns and conventions. This means skills and tools developed for S3 often transfer to other storage systems, making the broader storage landscape more accessible.

Despite all of this growth and industry adoption, perhaps the most remarkable achievement is this: the code you wrote for S3 in 2006 still works today, unchanged. Your data went through 20 years of innovation and technical advances. We migrated the infrastructure through multiple generations of disks and storage systems. All the code to handle a request has been rewritten. But the data you stored 20 years ago is still available today, and we’ve maintained complete API backward compatibility. That’s our commitment to delivering a service that continually “just works.”

The engineering behind the scale
What makes S3 possible at this scale? Continuous innovation in engineering.

Much of what follows is drawn from a conversation between Mai-Lan Tomsen Bukovec, VP of Data and Analytics at AWS, and Gergely Orosz of The Pragmatic Engineer. The in-depth interview goes further into the technical details for those who want to go deeper. In the following paragraphs, I share some examples:

At the heart of S3 durability is a system of microservices that continuously inspect every single byte across the entire fleet. These auditor services examine data and automatically trigger repair systems the moment they detect signs of degradation. S3 is designed to be lossless: the 11 nines design goal reflects how the replication factor and re-replication fleet are sized, but the system is built so that objects aren’t lost.

S3 engineers use formal methods and automated reasoning in production to mathematically prove correctness. When engineers check in code to the index subsystem, automated proofs verify that consistency hasn’t regressed. This same approach proves correctness in cross-Region replication or for access policies.

Over the past 8 years, AWS has been progressively rewriting performance-critical code in the S3 request path in Rust. Blob movement and disk storage have been rewritten, and work is actively ongoing across other components. Beyond raw performance, Rust’s type system and memory safety guarantees eliminate entire classes of bugs at compile time. This is an essential property when operating at S3 scale and correctness requirements.

S3 is built on a design philosophy: “Scale is to your advantage.” Engineers design systems so that increased scale improves attributes for all users. The larger S3 gets, the more de-correlated workloads become, which improves reliability for everyone.

Looking forward
The vision for S3 extends beyond being a storage service to becoming the universal foundation for all data and AI workloads. Our vision is simple: you store any type of data one time in S3, and you work with it directly, without moving data between specialized systems. This approach reduces costs, eliminates complexity, and removes the need for multiple copies of the same data.

Here are a few standout launches from recent years:

  • S3 Tables – Fully managed Apache Iceberg tables with automated maintenance that optimize query efficiency and reduce storage cost over time.
  • S3 Vectors – Native vector storage for semantic search and RAG, supporting up to 2 billion vectors per index with sub-100ms query latency. In only 5 months (July–December 2025), you created more than 250,000 indices, ingested more than 40 billion vectors, and performed more than 1 billion queries.
  • S3 Metadata – Centralized metadata for instant data discovery, removing the need to recursively list large buckets for cataloging and significantly reducing time-to-insight for large data lakes.

Each of these capabilities operates at S3 cost structure. You can handle multiple data types that traditionally required expensive databases or specialized systems but are now economically feasible at scale.

From 1 petabyte to hundreds of exabytes. From 15 cents to 2 cents per gigabyte. From simple object storage to the foundation for AI and analytics. Through it all, our five fundamentals–security, durability, availability, performance, and elasticity–remain unchanged, and your code from 2006 still works today.

Here’s to the next 20 years of innovation on Amazon S3.

— seb

AWS Weekly Roundup: Amazon Connect Health, Bedrock AgentCore Policy, GameDay Europe, and more (March 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-connect-health-bedrock-agentcore-policy-gameday-europe-and-more-march-9-2026/

Fiti AWS Student Community Kenya!

Last week was an incredible whirlwind: a round of meetups, hands-on workshops, and career discussions across Kenya that culminated with the AWS Student Community Day at Meru University of Science and Technology, with keynotes from my colleagues Veliswa and Tiffany, and sessions on everything from GitOps to cloud-native engineering, and a whole lot of AI agent building.

JAWS Days 2026 is the largest AWS Community Day in the world, with over 1,500 attendees on March 7th. This event started with a keynote speech on building an AI-driven development team by Jeff Barr, and included over 100 technical and community experience sessions, lightning talks, and workshops such as Game Days, Builders Card Challenges, and networking parties.

Now, let’s get into this week’s AWS news…

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Introducing Amazon Connect Health, Agentic AI Built for Healthcare — Amazon Connect Health is now generally available with five purpose-built AI agents for healthcare: patient verification, appointment management, patient insights, ambient documentation, and medical coding. All features are HIPAA-eligible and deployable within existing clinical workflows in days.
  • Policy in Amazon Bedrock AgentCore is now generally available — You can now use centralized, fine-grained controls for agent-tool interactions that operate outside your agent code. Security and compliance teams can define tool access and input validation rules using natural language that automatically converts to Cedar, the AWS open-source policy language.
  • Introducing OpenClaw on Amazon Lightsail to run your autonomous private AI agents — You can deploy a private AI assistant on your own cloud infrastructure with built-in security controls, sandboxed agent sessions, one-click HTTPS, and device pairing authentication. Amazon Bedrock serves as the default model provider, and you can connect to Slack, Telegram, WhatsApp, and Discord.
  • AWS announces pricing for VPC Encryption Controls — Starting March 1, 2026, VPC Encryption Controls transitions from free preview to a paid feature. You can audit and enforce encryption-in-transit of all traffic flows within and across VPCs in a region, with monitor mode to detect unencrypted traffic and enforce mode to prevent it.
  • Database Savings Plans now supports Amazon OpenSearch Service and Amazon Neptune Analytics — You can save up to 35% on eligible serverless and provisioned instance usage with a one-year commitment. Savings Plans automatically apply regardless of engine, instance family, size, or AWS Region.
  • AWS Elastic Beanstalk now offers AI-powered environment analysis — When your environment health is degraded, Elastic Beanstalk can now collect recent events, instance health, and logs and send them to Amazon Bedrock for analysis, providing step-by-step troubleshooting recommendations tailored to your environment’s current state.
  • AWS simplifies IAM role creation and setup in service workflows — You can now create and configure IAM roles directly within service workflows through a new in-console panel, without switching to the IAM console. The feature supports Amazon EC2, Lambda, EKS, ECS, Glue, CloudFormation, and more.
  • Accelerate Lambda durable functions development with new Kiro power — You can now build resilient, long-running multi-step applications and AI workflows faster with AI agent-assisted development in Kiro. The power dynamically loads guidance on replay models, step and wait operations, concurrent execution patterns, error handling, and deployment best practices.
  • Amazon GameLift Servers launches DDoS Protection — You can now protect session-based multiplayer games against DDoS attacks with a co-located relay network that authenticates client traffic using access tokens and enforces per-player traffic limits, at no additional cost to GameLift Servers customers.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

From AWS community
Here are my personal favorite posts from AWS community and my colleagues:

  • I Built a Portable AI Memory Layer with MCP, AWS Bedrock, and a Chrome Extension — Learn how to build a persistent memory layer for AI agents using MCP and Amazon Bedrock, packaged as a Chrome extension that carries context across sessions and applications.
  • When the Model Is the Machine — Mike Chambers built an experimental app where an AI agent generates a complete, interactive web application at runtime from a single prompt — no codebase, no framework, no persistent state. A thought-provoking exploration of what happens when the model becomes the runtime.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Community GameDay Europe — Think you know AWS? Prove it at the AWS Community GameDay Europe on March 17, a gamified learning event where teams compete to solve real-world technical challenges using AWS services.
  • AWS at NVIDIA GTC 2026 — Join us at our AWS sessions, booths, demos, and ancillary events in NVIDIA GTC 2026 on March 16 – 19, 2026 in San Jose. You can receive 20% off event passes through AWS and request a 1:1 meeting at GTC.
  • AWS Summits — Join AWS Summits in 2026: free in-person events where you can explore emerging cloud and AI technologies, learn best practices, and network with industry peers and experts. Upcoming Summits include Paris (April 1), London (April 22), and Bengaluru (April 23–24).
  • AWS Community Days — Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include Slovakia (March 11), Pune (March 21), and the AWSome Women Summit LATAM in Mexico City (March 28)

Browse here for upcoming AWS led in-person and virtual events, startup events, and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— seb

AWS Weekly Roundup: Claude Opus 4.6 in Amazon Bedrock, AWS Builder ID Sign in with Apple, and more (February 9, 2026)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-claude-opus-4-6-in-amazon-bedrock-aws-builder-id-sign-in-with-apple-and-more-february-9-2026/

Here are the notable launches and updates from last week that can help you build, scale, and innovate on AWS.

Last week’s launches
Here are the launches that got my attention this week.

Let’s start with news related to compute and networking infrastructure:

  • Introducing Amazon EC2 C8id, M8id, and R8id instances: These new Amazon EC2 C8id, M8id, and R8id instances are powered by custom Intel Xeon 6 processors. These instances offer up to 43% higher performance and 3.3x more memory bandwidth compared to previous generation instances.
  • AWS Network Firewall announces new price reductions: The service has added the hourly and data processing discounts on NAT Gateways that are service-chained with Network Firewall secondary endpoints. Additionally, AWS Network Firewall has removed additional data processing charges for Advanced Inspection, which enables Transport Layer Security (TLS) inspection of encrypted network traffic.
  • Amazon ECS adds Network Load Balancer support for Linear and Canary deployments: Applications that commonly use NLB, such as those requiring TCP/UDP-based connections, low latency, long-lived connections, or static IP addresses, can take advantage of managed, incremental traffic shifting natively from ECS when rolling out updates.
  • AWS Config now supports 30 new resource types: These range across key services including Amazon EKS, Amazon Q, and AWS IoT. This expansion provides greater coverage over your AWS environment, enabling you to more effectively discover, assess, audit, and remediate an even broader range of resources.
  • Amazon DynamoDB global tables now support replication across multiple AWS accounts: DynamoDB global tables are a fully managed, serverless, multi-Region, and multi-active database. With this new capability, you can replicate tables across AWS accounts and Regions to improve resiliency, isolate workloads at the account level, and apply distinct security and governance controls.
  • Amazon RDS now provides an enhanced console experience to connect to a database: The new console experience provides ready-made code snippets for Java, Python, Node.js, and other programming languages as well as tools like the psql command line utility. These code snippets are automatically adjusted based on your database’s authentication settings. For example, if your cluster uses IAM authentication, the generated code snippets will use token-based authentication to connect to the database. The console experience also includes integrated CloudShell access, offering the ability to connect to your databases directly from within the RDS console.

Then, I noticed three news items related to security and how you authenticate on AWS:

  • AWS Builder ID now supports Sign in with Apple: AWS Builder ID, your profile for accessing AWS applications including AWS Builder Center, AWS Training and Certification, AWS re:Post, AWS Startups, and Kiro, now supports sign-in with Apple as a social login provider. This expansion of sign-in options builds on the existing sign-in with Google capability, providing Apple users with a streamlined way to access AWS resources without managing separate credentials on AWS.
  • AWS STS now supports validation of select identity provider specific claims from Google, GitHub, CircleCI and OCI: You can reference these custom claims as condition keys in IAM role trust policies and resource control policies, expanding your ability to implement fine-grained access control for federated identities and help you establish your data perimeters. This enhancement builds upon IAM’s existing OIDC federation capabilities, which allow you to grant temporary AWS credentials to users authenticated through external OIDC-compatible identity providers.
  • AWS Management Console now displays Account Name on the Navigation bar for easier account identification: You now have an easy way to identify your accounts at a glance. You can now quickly distinguish between accounts visually using the account name that appears in the navigation bar for all authorized users in that account.
  • Amazon CloudFront announces mutual TLS support for origins: Now with origin mTLS support, you can implement a standardized, certificate-based authentication approach that eliminates operational burden. This enables organizations to enforce strict authentication for their proprietary content, ensuring that only verified CloudFront distributions can establish connections to backend infrastructure ranging from AWS origins and on-premises servers to third-party cloud providers and external CDNs.

Finally, there is not a single week without news around AI :

  • Claude Opus 4.6 now available in Amazon Bedrock: Opus 4.6 is Anthropic’s most intelligent model to date and a premier model for coding, enterprise agents, and professional work. Claude Opus 4.6 brings advanced capabilities to Amazon Bedrock customers, including industry-leading performance for agentic tasks, complex coding projects, and enterprise-grade workflows that require deep reasoning and reliability.
  • Structured outputs now available in Amazon Bedrock: Amazon Bedrock now supports structured outputs, a capability that provides consistent, machine-readable responses from foundation models that adhere to your defined JSON schemas. Instead of prompting for valid JSON and adding extra checks in your application, you can specify the format you want and receive responses that match it—making production workflows more predictable and resilient.

Upcoming AWS events
Check your calendars so that you can sign up for this upcoming event:

AWS Community Day Romania (April 23–24, 2026): This community-led AWS event brings together developers, architects, entrepreneurs, and students for more than 10 professional sessions delivered by AWS Heroes, Solutions Architects, and industry experts. Attendees can expect expert-led technical talks, insights from speakers with global conference experience, and opportunities to connect during dedicated networking breaks, all hosted at a premium venue designed to support collaboration and community engagement.

If you’re looking for more ways to stay connected beyond this event, join the AWS Builder Center to learn, build, and connect with builders in the AWS community.

Check back next Monday for another Weekly Roundup.

— seb

Opening the AWS European Sovereign Cloud

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/opening-the-aws-european-sovereign-cloud/

Deutsch | English | Español | Français | Italiano

As a European citizen, I understand first-hand the importance of digital sovereignty, especially for our public sector organisations and highly regulated industries. Today, I’m delighted to share that the AWS European Sovereign Cloud is now generally available to all customers. We first announced our plans to build this new independent cloud infrastructure in 2023, and today it’s ready to meet the most stringent sovereignty requirements of European customers with a comprehensive set of AWS services.

Brandenburg Gate

Berlin, Brandenburg Gate at sunset

Meeting European sovereignty requirements
Organizations across Europe face increasingly complex regulatory requirements around data residency, operational control, and governance independence. Too often today, European organisations with the highest sovereignty requirements are stuck in legacy on-premises environments or offerings with reduced services and functionality. In response to this critical need, the AWS European Sovereign Cloud is the only fully featured and independently operated sovereign cloud backed by strong technical controls, sovereign assurances, and legal protections. Public sector entities and businesses in highly regulated industries need cloud infrastructure that provides enhanced sovereignty controls that maintain the innovation, security, and reliability they expect from modern cloud services. These organisations require assurance that their data and operations remain under European jurisdiction, with clear governance structures and operational autonomy within the European Union (EU).

A new independent cloud infrastructure for Europe
The AWS European Sovereign Cloud represents a physically and logically separate cloud infrastructure, with all components located entirely within the EU. The first AWS Region in the AWS European Sovereign Cloud is located in the state of Brandenburg, Germany, and is generally available today. This Region operates independently from existing AWS Regions. The infrastructure features multiple Availability Zones with redundant power and networking, designed to operate continuously even if connectivity with the rest of the world is interrupted.

We plan to extend the AWS European Sovereign Cloud footprint from Germany across the EU to support stringent isolation, in-country data residency, and low latency requirements. This will start with new sovereign Local Zones located in Belgium, the Netherlands, and Portugal. In addition, you will be able to extend the AWS European Sovereign Cloud infrastructure with AWS Dedicated Local Zones, AWS AI Factories, or AWS Outposts in locations you select, including your own on-premises data centres.

The AWS European Sovereign Cloud and its Local Zones provide enhanced sovereign controls through its unique operational model. The AWS European Sovereign Cloud will be operated exclusively by EU residents located in the EU. This covers activities such as day-to-day operations, technical support, and customer service. We’re gradually transitioning the AWS European Sovereign Cloud to be operated exclusively by EU citizens located in the EU. During this transition period, we will continue to work with a blended team of EU residents and EU citizens located in the EU.

The infrastructure is managed through dedicated European legal entities established under German law. In October 2025, AWS appointed Stéphane Israël, an EU citizen residing in the EU, as managing director. Stéphane will be responsible for the management and operations of the AWS European Sovereign Cloud, including infrastructure, technology, and services, as well as leading AWS broader digital sovereignty efforts. In January 2026, AWS also appointed Stefan Hoechbauer (Vice President, Germany and Central Europe, AWS) as a managing director of the AWS European Sovereign Cloud. He will work alongside Stéphane Israel to lead the AWS European Sovereign Cloud.

An advisory board comprised exclusively of EU citizens, and including two independent third-party representatives, provides additional oversight and expertise on sovereignty matters.

Enhanced data residency and control
The AWS European Sovereign Cloud provides comprehensive data residency assurances so you can meet the most stringent data residency requirements. As with our existing AWS Regions around the world, all your content remains within the Region you select unless you choose otherwise. Beyond content, customer-created metadata including roles, permissions, resource labels, and configurations also stays within the EU. The infrastructure features its own dedicated AWS Identity and Access Management (IAM) and billing system, all operating independently within European borders.

Technical controls built into the infrastructure prevent access to the AWS European Sovereign Cloud from outside the EU. The infrastructure includes a dedicated European trust service provider for certificate authority operations and uses dedicated Amazon Route 53 name servers. These servers will only use European Top-Level Domains (TLDs) for their own names. The AWS European Sovereign Cloud has no critical dependencies on non-EU personnel or infrastructure.

Security and compliance framework
The AWS European Sovereign Cloud maintains the same core security capabilities you expect from AWS, including encryption, key management, access governance, and the AWS Nitro System for compute isolation. This means your EC2 instances benefit from cryptographically verified platform integrity and hardware-enforced boundaries that prevent unauthorized access to your data without compromising on performance, giving you both the sovereignty controls and the computational power your workloads require. The infrastructure undergoes independent third-party audits, with compliance programs including ISO/IEC 27001:2013, SOC 1/2/3 reports, and Federal Office for Information Security (BSI) C5 attestation.

The AWS European Sovereign Cloud: Sovereign Reference Framework defines the specific sovereignty controls across governance independence, operational control, data residency, and technical isolation. This framework is available in AWS Artifact and provides end-to-end visibility through SOC 2 attestation.

Comprehensive service availability
You can access a broad range of AWS services in the AWS European Sovereign Cloud from launch, including Amazon SageMaker and Amazon Bedrock for artificial intelligence and machine learning (AI/ML) workloads. For compute, you can use Amazon Elastic Compute Cloud (Amazon EC2) and AWS Lambda. Container orchestration is available through Amazon Elastic Kubernetes Service (Amazon EKS) and Amazon Elastic Container Service (Amazon ECS). Database services include Amazon Aurora, Amazon DynamoDB, and Amazon Relational Database Service (Amazon RDS). Storage options include Amazon Simple Storage Service (Amazon S3) and Amazon Elastic Block Store (Amazon EBS), with networking through Amazon Virtual Private Cloud (Amazon VPC) and security services including AWS Key Management Service (AWS KMS) and AWS Private Certificate Authority. For an up-to-date list of services, refer to the AWS Capabilities matrix recently published on the AWS Builder Center.

The AWS European Sovereign Cloud is supported by AWS Partners who are committed to helping you meet your sovereignty requirements. Partners including Adobe, Cisco, Cloudera, Dedalus, Esri, Genesys, GitLab, Mendix, Pega, SAP, SnowFlake, Trend Micro, and Wiz are making their solutions available in the AWS European Sovereign Cloud, providing you with the tools and services you need across security, data analytics, application development, and industry-specific workloads. This broad partner support helps you build sovereign solutions that combine AWS services with trusted partner technologies.

Significant investment in European infrastructure
The AWS European Sovereign Cloud is backed by a €7.8 billion investment in infrastructure, jobs creation, and skills development. This investment is expected to contribute €17.2 billion to the European economy through 2040 and support roughly 2,800 full-time equivalent jobs annually in local businesses.

Some technical details
The AWS European Sovereign Cloud is available to all customers, regardless of where they are located. You can access the infrastructure using the partition name aws-eusc and the Region name eusc-de-east-1. A partition is a group of AWS Regions. Each AWS account is scoped to one partition.

The infrastructure supports all standard AWS access methods including the AWS Management Console, AWS SDKs, and the AWS Command Line Interface (AWS CLI), making it straightforward to integrate into your existing workflows and automation. After having created a new root account for the AWS European Sovereign Cloud partition, you start by creating new IAM identities and roles specific to this infrastructure, giving you complete control over access management within the European sovereign environment.

Getting started
The AWS European Sovereign Cloud provides European organisations with enhanced sovereignty controls whilst maintaining access to AWS innovation and capabilities. You can contract for services through Amazon Web Services EMEA SARL, with pricing in EUR and billing in any of the eight currencies we support today. The infrastructure uses familiar AWS architecture, service portfolio, and APIs, making it straightforward to build and migrate applications.

The AWS European Sovereign Cloud addendum contains the additional contractual commitments for the AWS European Sovereign Cloud.

For me as a European, this launch represents the AWS commitment to meeting the specific needs of our continent and providing the cloud capabilities that drive innovation across industries. I invite you to find out more about the AWS European Sovereign Cloud and how it can help your organisation meet its sovereignty requirements. Read Overview of the AWS European Sovereign Cloud to learn more about the design goals and approach, sign up for a new account, and plan for the deployment of your first workload today.

— seb


German version

Start der AWS European Sovereign Cloud

Als Bürger Europas weiß ich aus eigener Erfahrung, wie wichtig digitale Souveränität ist, insbesondere für unsere öffentlichen Einrichtungen und stark regulierten Branchen. Ich freue mich, Ihnen heute mitteilen zu können, dass die AWS European Sovereign Cloud nun für alle Kunden allgemein verfügbar ist. Wir haben unsere Pläne zum Aufbau dieser neuen unabhängigen Cloud-Infrastruktur erstmals im Jahr 2023 vorgestellt. Heute ist diese Infrastruktur bereit, mit einem umfassenden Angebot an AWS-Services die strengsten Souveränitätsanforderungen europäischer Kunden zu erfüllen.

Brandenburg Gate

Berlin, Brandenburger Tor bei Sonnenuntergang

Erfüllung europäischer Souveränitätsanforderungen
Organisationen in ganz Europa sehen sich mit zunehmend komplexen regulatorischen Anforderungen in Bezug auf Datenresidenz, operative Kontrolle und Unabhängigkeit der Governance konfrontiert. Europäische Organisationen mit höchsten Souveränitätsanforderungen sind heutzutage allzu oft in veralteten lokalen Umgebungen oder Angeboten mit eingeschränkten Services und Funktionen gefangen. Die AWS European Sovereign Cloud ist die Antwort auf diesen dringenden Bedarf. Sie ist die einzige unabhängig betriebene souveräne Cloud mit vollem Funktionsumfang, die durch strenge technische Kontrollen, Souveränitätszusicherungen und rechtlichen Schutz abgesichert ist. Einrichtungen des öffentlichen Sektors und Unternehmen in stark regulierten Branchen benötigen eine Cloud-Infrastruktur, die erweiterte Souveränitätskontrollen bietet und gleichzeitig die von modernen Cloud-Services erwartete Innovation, Sicherheit und Zuverlässigkeit gewährleistet. Diese Organisationen benötigen die Zusicherung, dass ihre Daten und Aktivitäten unter europäischer Zuständigkeit bleiben, mit klaren Governance-Strukturen und operativer Autonomie innerhalb der Europäischen Union (EU).

Eine neue unabhängige Cloud-Infrastruktur für Europa
Die AWS European Sovereign Cloud ist eine physisch und logisch getrennte Cloud-Infrastruktur, deren Komponenten sich vollständig innerhalb der EU befinden. Die erste AWS-Region in der AWS European Sovereign Cloud befindet sich im deutschen Bundesland Brandenburg und ist ab heute allgemein verfügbar. Diese Region arbeitet unabhängig von bestehenden AWS-Regionen. Die Infrastruktur umfasst mehrere Availability Zones mit redundanter Stromversorgung und Netzwerkverbindung, die auch bei einer Unterbrechung der Verbindung zum Rest der Welt einen kontinuierlichen Betrieb gewährleisten.

Wir beabsichtigen, die Präsenz der AWS European Sovereign Cloud von Deutschland aus EU-weit auszuweiten, um strenge Anforderungen hinsichtlich Isolierung, Datenresidenz innerhalb einzelner Länder und geringer Latenz zu erfüllen. Dies beginnt mit neuen souveränen Local Zones in Belgien, den Niederlanden und Portugal. Darüber hinaus können Sie die Infrastruktur der AWS European Sovereign Cloud mit dedizierten AWS Local Zones, AWS AI Factories oder AWS Outposts an Standorten Ihrer Wahl, einschließlich Ihrer eigenen lokalen Rechenzentren, erweitern.

Dank ihres einzigartigen Betriebsmodells bieten die AWS European Sovereign Cloud und ihre Local Zones erweiterte Souveränitätskontrollen. Der Betrieb der AWS European Sovereign Cloud wird ausschließlich von EU-Bürgern mit Wohnsitz in der EU sichergestellt. Dies umfasst Aktivitäten wie den täglichen Betrieb, den technischen Support und den Kundenservice. Wir stellen die AWS European Sovereign Cloud schrittweise so um, dass als Betriebspersonal ausschließlich EU-Bürger mit Wohnsitz in der EU zum Einsatz kommen. Während dieser Übergangsphase werden wir weiterhin mit einem gemischten Team aus in der EU ansässigen Personen und in der EU lebenden EU-Bürgern arbeiten.

Die Infrastruktur wird durch spezielle europäische juristische Personen nach deutschem Recht verwaltet. Im Oktober 2025 berief AWS Stéphane Israël, einen in der EU ansässigen EU-Bürger, zum Geschäftsführer. Stéphane wird für das Management und den Betrieb der AWS European Sovereign Cloud verantwortlich zeichnen. Dies umfasst die Bereiche Infrastruktur, Technologie und Services sowie die Federführung bei den breit angelegten Initiativen von AWS auf dem Gebiet der digitalen Souveränität. Im Januar 2026 ernannte AWS zudem Stefan Hoechbauer (Vice President, Germany and Central Europe, AWS) zum Geschäftsführer der AWS European Sovereign Cloud. Er wird gemeinsam mit Stéphane Israel die Leitung der AWS European Sovereign Cloud innehaben.

Ein Beirat, dem ausschließlich EU-Bürger, einschließlich zwei unabhängigen externen Vertretern, angehören, fungiert als zusätzliche Kontrollinstanz und bringt Fachwissen in Fragen der Souveränität ein.

Verbesserte Datenresidenz und -kontrolle
Die AWS European Sovereign Cloud bietet umfassende Garantien hinsichtlich der Datenresidenz, sodass Sie selbst die strengsten Anforderungen in diesem Bereich erfüllen können. Wie auch bei unseren bestehenden AWS-Regionen weltweit verbleiben alle Ihre Inhalte in der von Ihnen ausgewählten Region, sofern Sie keine anderen Einstellungen vornehmen. Neben den Inhalten verbleiben auch die vom Kunden erstellten Metadaten, einschließlich Rollen, Berechtigungen, Ressourcenbezeichnungen und Konfigurationen, innerhalb der EU. Die Infrastruktur verfügt über ein eigenes AWS Identity and Access Management (IAM) und ein eigenes Abrechnungssystem – beides wird innerhalb der europäischen Grenzen unabhängig betrieben.

In die Infrastruktur integrierte technische Kontrollen verhindern den Zugriff auf die AWS European Sovereign Cloud von außerhalb der EU. Die Infrastruktur umfasst einen dedizierten europäischen Trust Service Provider für Zertifizierungsstellen und nutzt dedizierte Amazon-Route-53-Namenserver. Diese Server verwenden ausschließlich europäische Top-Level-Domains (TLDs) für ihre eigenen Namen. Die AWS European Sovereign Cloud unterliegt keinen kritischen Abhängigkeiten hinsichtlich Personal oder Infrastruktur außerhalb der EU.

Sicherheits- und Compliance-Framework
Die AWS European Sovereign Cloud bietet dieselben zentralen Sicherheitsfunktionen, die Sie von AWS erwarten. Dazu gehören Verschlüsselung, Schlüsselverwaltung, Zugriffskontrolle und das AWS Nitro System für die Isolierung von Rechenressourcen. Dies bedeutet, dass Ihre EC2-Instanzen von einer kryptografisch verifizierten Plattformintegrität und hardwaregestützten Grenzen profitieren, die unbefugten Zugriff auf Ihre Daten verhindern, ohne die Leistung zu beeinträchtigen. So erhalten Sie sowohl die Souveränitätskontrollen als auch die Rechenleistung, die Ihre Workloads erfordern. Die Infrastruktur wird unabhängigen Audits durch Dritte unterzogen. Die Compliance-Programme umfassen ISO/IEC 27001:2013, SOC-1/2/3-Berichte und das C5-Zertifikat des Bundesamtes für Sicherheit in der Informationstechnik (BSI).

Das AWS European Sovereign Cloud: Sovereign Reference Framework definiert spezifische Souveränitätskontrollen in den Bereichen Governance-Unabhängigkeit, operative Kontrolle, Datenresidenz und technische Isolierung. Dieses Framework ist in AWS Artifact verfügbar und bietet durch SOC-2-Zertifizierung durchgängige Transparenz.

Umfassende Serviceverfügbarkeit
Von Beginn an steht Ihnen in der AWS European Sovereign Cloud eine breite Palette von AWS-Services zur Verfügung – darunter Amazon SageMaker und Amazon Bedrock für Workloads im Bereich Künstliche Intelligenz und Machine Learning (KI/ML). Für die Rechenleistung stehen Ihnen Amazon Elastic Compute Cloud (Amazon EC2) und AWS Lambda zur Verfügung. Die Container-Orchestrierung ist über den Amazon Elastic Kubernetes Service (Amazon EKS) und den Amazon Elastic Container Service (Amazon ECS) verfügbar. Zu den Datenbank-Services gehören Amazon Aurora, Amazon DynamoDB und Amazon Relational Database Service (Amazon RDS). Die Speicheroptionen umfassen Amazon Simple Storage Service (Amazon S3) und Amazon Elastic Block Store (Amazon EBS) mit Vernetzung über Amazon Virtual Private Cloud (Amazon VPC) und Sicherheits-Services wie AWS Key Management Service (AWS KMS) und AWS Private Certificate Authority. Eine aktuelle Liste der Services finden Sie in der AWS-Funktionsmatrix, die kürzlich im AWS Builder Center veröffentlicht wurde.

Die AWS European Sovereign Cloud wird von AWS-Partnern unterstützt, die es sich zur Aufgabe gemacht haben, Ihnen bei der Erfüllung Ihrer Souveränitätsanforderungen zur Seite zu stehen. Partner wie Adobe, Cisco, Cloudera, Dedalus, Esri, Genesys, GitLab, Mendix, Pega, SAP, SnowFlake, Trend Micro und Wiz stellen ihre Lösungen in der AWS European Sovereign Cloud zur Verfügung und bieten Ihnen die Tools und Services, die Sie in den Bereichen Sicherheit, Datenanalyse, Entwicklung von Anwendungen und branchenspezifische Workloads benötigen. Dank dieser umfassenden Unterstützung durch Partner können Sie eigenständige Lösungen, die AWS-Services mit bewährten Partnertechnologien kombinieren, entwickeln.

Erhebliche Investitionen in die europäische Infrastruktur
Hinter der AWS European Sovereign Cloud steht eine Investition in Höhe von 7,8 Milliarden Euro in Infrastruktur, die Schaffung von Arbeitsplätzen und die Entwicklung von Kompetenzen. Diese Investition wird bis 2040 voraussichtlich 17,2 Milliarden Euro zur europäischen Wirtschaftsleistung beitragen und jährlich rund 2 800 Vollzeitstellen in lokalen Unternehmen sichern.

Einige technische Details
Die AWS European Sovereign Cloud steht allen Kunden zur Verfügung, unabhängig davon, wo sie sich befinden. Sie können mit dem Partitionsnamen aws-eusc und dem Regionsnamen eusc-de-east-1 auf die Infrastruktur zugreifen. Eine Partition ist eine Gruppe von AWS-Regionen. Jedes AWS-Konto ist auf eine Partition beschränkt.

Die Infrastruktur unterstützt alle gängigen AWS-Zugriffsmethoden, einschließlich der AWS Management Console, AWS SDKs und der AWS Command Line Interface (AWS CLI), sodass sie sich problemlos in Ihre bestehenden Workflows und Automatisierungsprozesse integrieren lässt. Nachdem Sie ein neues Root-Konto für die Partition der AWS European Sovereign Cloud erstellt haben, beginnen Sie mit der Erstellung neuer IAM-Identitäten und -Rollen, die speziell für diese Infrastruktur vorgesehen sind. Dadurch erhalten Sie die vollständige Kontrolle über die Zugriffsverwaltung innerhalb der europäischen souveränen Umgebung.

Erste Schritte
Die AWS European Sovereign Cloud bietet europäischen Organisationen erweiterte Souveränitätskontrollen und gewährleistet gleichzeitig den Zugriff auf die Innovationen und Funktionen von AWS. Sie können Services über Amazon Web Services EMEA SARL in Auftrag geben. Die Preise werden in Euro angegeben und die Abrechnung erfolgt in einer der acht Währungen, die wir derzeit unterstützen. Die Infrastruktur basiert auf der bekannten AWS-Architektur, dem AWS-Serviceportfolio und den AWS-APIs, wodurch die Entwicklung und Migration von Anwendungen vereinfacht wird.

Der AWS European Sovereign Cloud Addendum enthält die zusätzlichen vertraglichen Verpflichtungen für die AWS European Sovereign Cloud.

Für mich als Europäer symbolisiert dieser Launch das Engagement von AWS, den spezifischen Anforderungen unseres Kontinents gerecht zu werden und Cloud-Funktionen bereitzustellen, die Innovationen in allen Branchen vorantreiben. Ich lade Sie ein, mehr über die AWS European Sovereign Cloud zu erfahren und zu entdecken, wie sie Ihrer Organisation dabei helfen kann, ihre Souveränitätsanforderungen zu erfüllen. Lesen Sie die Übersicht über die AWS European Sovereign Cloud und erfahren Sie mehr über die Designziele und den Ansatz. Registrieren Sie sich für ein neues Konto und planen Sie noch heute die Bereitstellung Ihrer ersten Workload.

— seb


French version

Ouverture de l’AWS European Souvereign Cloud

En tant que citoyen européen, je mesure personnellement l’importance de la souveraineté numérique, en particulier pour nos organisations du secteur public et les industries fortement réglementées. Aujourd’hui, j’ai le plaisir d’annoncer que l’AWS European Sovereign Cloud est désormais disponible pour l’ensemble de nos clients. Nous avions annoncé pour la première fois notre projet de construction de cette nouvelle infrastructure cloud indépendante en 2023, et elle est aujourd’hui prête à répondre aux exigences de souveraineté les plus strictes des clients européens, avec un large ensemble de services AWS.

Brandenburg Gate

Berlin, porte de Brandebourg au coucher du soleil

Répondre aux exigences européennes en matière de souveraineté
Partout en Europe, les organisations sont confrontées à des exigences réglementaires de plus en plus complexes en matière de résidence des données, de contrôle opérationnel et d’indépendance de la gouvernance. Trop souvent aujourd’hui, les organisations européennes ayant les besoins de souveraineté les plus élevés se retrouvent contraintes de rester sur des environnements sur site, ou de recourir à des offres cloud aux services et fonctionnalités limités. Pour répondre à cet enjeu critique, l’AWS European Sovereign Cloud est le seul cloud souverain entièrement fonctionnel, exploité de manière indépendante, et reposant sur des contrôles techniques robustes, des garanties de souveraineté et des protections juridiques solides. Les acteurs du secteur public et les entreprises des secteurs fortement réglementés ont besoin d’une infrastructure cloud offrant des contrôles de souveraineté renforcés, sans renoncer à l’innovation, à la sécurité et à la fiabilité attendues des services cloud modernes. Ces organisations doivent avoir l’assurance que leurs données et leurs opérations restent sous juridiction européenne, avec des structures de gouvernance claires et une autonomie opérationnelle au sein de l’Union européenne (UE).

Une nouvelle infrastructure cloud indépendante pour l’Europe
L’AWS European Sovereign Cloud repose sur une infrastructure cloud physiquement et logiquement distincte, dont l’ensemble des composants est situé exclusivement au sein de l’UE. La première région AWS de l’AWS European Sovereign Cloud est implantée dans le Land de Brandebourg, en Allemagne, et est disponible dès aujourd’hui. Cette région fonctionne de façon indépendante par rapport aux autres régions AWS existantes. L’infrastructure comprend plusieurs zones de disponibilité, avec des systèmes redondants d’alimentation et de réseau, conçus pour fonctionner en continu même en cas d’interruption de la connectivité avec le reste du monde.

Nous prévoyons d’étendre l’empreinte de l’AWS European Sovereign Cloud depuis l’Allemagne à l’ensemble de l’UE, afin de répondre aux exigences strictes d’isolation, de résidence des données dans certains pays et de faible latence. Cette extension débutera avec de nouvelles Local Zones souveraines situées en Belgique, aux Pays-Bas et au Portugal. En complément, vous pourrez étendre l’infrastructure de l’AWS European Sovereign Cloud à l’aide des AWS Dedicated Local Zones, des AWS AI Factories ou d’AWS Outposts, dans les sites de votre choix, y compris au sein de vos propres centres de données sur site.

L’AWS European Sovereign Cloud et ses Local Zones offrent des contrôles de souveraineté renforcés grâce à un modèle opérationnel unique. L’AWS European Sovereign Cloud est exploité exclusivement par des résidents de l’UE basés dans l’UE. Cela couvre notamment les opérations quotidiennes, le support technique et le service client. Nous sommes en train d’opérer une transition progressive afin que l’AWS European Sovereign Cloud soit exploité exclusivement par des citoyens de l’UE résidant dans l’UE. Durant cette période de transition, nous continuons de travailler avec une équipe mixte composée de résidents de l’UE et de citoyens de l’UE basés dans l’UE.

L’infrastructure est gérée par des entités juridiques européennes dédiées, établies conformément au droit allemand. En octobre 2025, AWS a nommé Stéphane Israël, citoyen de l’UE résidant dans l’UE, au poste de directeur général. Stéphane est responsable de la gestion et de l’exploitation de l’AWS European Sovereign Cloud, couvrant l’infrastructure, la technologie et les services, ainsi que de la direction des initiatives plus larges d’AWS en matière de souveraineté numérique. En janvier 2026, AWS a également nommé Stefan Hoechbauer (Vice-président, Allemagne et Europe centrale, AWS) comme directeur général de l’AWS European Sovereign Cloud. Il travaillera aux côtés de Stéphane Israël pour piloter l’AWS European Sovereign Cloud.

Un conseil consultatif, composé exclusivement de citoyens de l’UE et incluant deux représentants indépendants, apporte un niveau supplémentaire de supervision et d’expertise sur les questions de souveraineté.

Résidence des données et contrôle renforcés
L’AWS European Sovereign Cloud fournit des garanties complètes en matière de résidence des données afin de répondre aux exigences les plus strictes. Comme dans les régions AWS existantes à travers le monde, l’ensemble de vos contenus reste dans la région que vous sélectionnez, sauf indication contraire de votre part. Au-delà des contenus, les métadonnées créées par les clients — telles que les rôles, les autorisations, les étiquettes de ressources et les configurations — restent également au sein de l’UE. L’infrastructure dispose de son propre système dédié de AWS Identity and Access Management (IAM) et de facturation, opérant de manière totalement indépendante à l’intérieur des frontières européennes.

Des contrôles techniques intégrés à l’infrastructure empêchent tout accès à l’AWS European Sovereign Cloud depuis l’extérieur de l’UE. L’infrastructure comprend un prestataire européen de services de confiance dédié pour les opérations d’autorité de certification et utilise des serveurs de noms Amazon Route 53 dédiés. Ces serveurs n’utilisent que des domaines de premier niveau (TLD) européens pour leurs propres noms. L’AWS European Sovereign Cloud ne présente aucune dépendance critique vis-à-vis de personnels ou d’infrastructures situés en dehors de l’UE.

Cadre de sécurité et de conformité
L’AWS European Sovereign Cloud conserve les capacités de sécurité fondamentales attendues d’AWS, notamment le chiffrement, la gestion des clés, la gouvernance des accès et le système AWS Nitro pour l’isolation des charges de calcul. Concrètement, vos instances EC2 bénéficient d’une intégrité de plateforme vérifiée cryptographiquement et de frontières matérielles, empêchant tout accès non autorisé à vos données sans compromis sur les performances. Vous bénéficiez ainsi à la fois des contrôles de souveraineté et de la puissance de calcul nécessaires à vos charges de travail. L’infrastructure fait l’objet d’audits indépendants réalisés par des tiers, et s’inscrit dans des programmes de conformité incluant ISO/IEC 27001:2013, les rapports SOC 1/2/3, ainsi que l’attestation C5 de l’Office fédéral allemand pour la sécurité de l’information (BSI).

Le AWS European Sovereign Cloud: Sovereign Reference Framework définit précisément les contrôles de souveraineté couvrant l’indépendance de la gouvernance, le contrôle opérationnel, la résidence des données et l’isolation technique. Ce cadre est disponible dans AWS Artifact et offre une visibilité de bout en bout via une attestation SOC 2.

Disponibilité étendue des services
Dès son lancement, l’AWS European Sovereign Cloud donne accès à un large éventail de services AWS, notamment Amazon SageMaker et Amazon Bedrock pour les charges de travail d’intelligence artificielle et de machine learning (IA/ML). Pour le calcul, vous pouvez utiliser Amazon Elastic Compute Cloud (Amazon EC2) et AWS Lambda. L’orchestration de conteneurs est disponible via Amazon Elastic Kubernetes Service (Amazon EKS) et Amazon Elastic Container Service (Amazon ECS). Les services de bases de données incluent Amazon Aurora, Amazon DynamoDB et Amazon Relational Database Service (Amazon RDS). Les options de stockage comprennent Amazon Simple Storage Service (Amazon S3) et Amazon Elastic Block Store (Amazon EBS), avec des capacités réseau via Amazon Virtual Private Cloud (Amazon VPC) et des services de sécurité tels que AWS Key Management Service (AWS KMS) et AWS Private Certificate Authority. Pour obtenir la liste la plus à jour des services disponibles, consultez la matrice des capacités AWS récemment publiée sur l’AWS Builder Center.

L’AWS European Sovereign Cloud est supporté par de nombreux partenaires AWS engagés à vous aider à répondre à vos exigences de souveraineté. Des partenaires tels qu’Adobe, Cisco, Cloudera, Dedalus, Esri, Genesys, GitLab, Mendix, Pega, SAP, SnowFlake, Trend Micro et Wiz rendent leurs solutions disponibles sur l’AWS European Sovereign Cloud, vous offrant ainsi les outils et services nécessaires dans les domaines de la sécurité, de l’analyse de données, du développement applicatif et des charges de travail spécifiques à certains secteurs industriels. Cet ensemble de partenaires vous permet de construire des solutions souveraines combinant les services AWS et des technologies de partenaires de confiance.

Un investissement majeur dans l’infrastructure européenne
L’AWS European Sovereign Cloud s’appuie sur un investissement de 7,8 milliards d’euros dans l’infrastructure, la création d’emplois et le développement des compétences. Cet investissement devrait contribuer à hauteur de 17,2 milliards d’euros à l’économie européenne d’ici 2040 et soutenir environ 2.800 emplois équivalent temps plein par an au sein des entreprises locales.

Quelques détails techniques
L’AWS European Sovereign Cloud est accessible à tous les clients, quel que soit leur lieu d’implantation. Vous pouvez accéder à l’infrastructure en utilisant le nom de partition aws-eusc et le nom de région eusc-de-east-1. Une partition correspond à un ensemble de régions AWS. Chaque compte AWS est rattaché à une seule partition.

L’infrastructure prend en charge toutes les méthodes d’accès AWS standards, y compris la console de gestion AWS, les AWS SDKs et la AWS Command Line Interface (AWS CLI), ce qui facilite son intégration dans vos flux de travail et vos automatisations existants. Après avoir créé un nouveau compte racine pour la partition AWS European Sovereign Cloud, vous commencez par définir de nouvelles identités et rôles IAM spécifiques à cette infrastructure, vous donnant un contrôle total sur la gestion des accès au sein de l’environnement souverain européen.

Pour commencer
L’AWS European Sovereign Cloud offre aux organisations européennes des contrôles de souveraineté renforcés tout en leur permettant de continuer à bénéficier de l’innovation et des capacités d’AWS. Vous pouvez contractualiser les services via Amazon Web Services EMEA SARL, avec une tarification en euros et une facturation possible dans l’une des huit devises que nous prenons en charge aujourd’hui. L’infrastructure repose sur une architecture, un portefeuille de services et des API AWS familiers, ce qui simplifie le développement et la migration des applications.

L’avenant AWS European Sovereign Cloud précise les engagements contractuels supplémentaires propres à l’AWS European Sovereign Cloud.

En tant qu’Européen, ce lancement illustre l’engagement d’AWS à répondre aux besoins spécifiques de notre continent et à fournir les capacités cloud qui stimulent l’innovation dans tous les secteurs. Je vous invite à découvrir l’AWS European Sovereign Cloud et à comprendre comment il peut aider votre organisation à satisfaire ses exigences de souveraineté. Consultez Overview of the AWS European Sovereign Cloud (en anglais) pour en savoir plus sur les objectifs de conception et l’approche retenue, créez un nouveau compte et planifiez dès aujourd’hui le déploiement de votre première charge de travail.

— seb


Italian version

Lancio di AWS European Sovereign Cloud

Come cittadino europeo, conosco benissimo l’importanza della sovranità digitale, in particolare per le nostre organizzazioni del settore pubblico e dei settori altamente regolamentati. Oggi sono lieto di annunciare che AWS European Sovereign Cloud è ora generalmente disponibile per tutti i clienti. Abbiamo annunciato per la prima volta i nostri piani per la creazione di questa nuova infrastruttura cloud indipendente nel 2023. Finalmente oggi è pronta a soddisfare i più rigorosi requisiti di sovranità dei clienti europei con un set completo di servizi AWS.

Brandenburg Gate

Berlino, Porta di Brandeburgo al tramonto

Soddisfare i requisiti di sovranità europea
Le organizzazioni di tutta Europa devono far fronte a requisiti normativi sempre più complessi in materia di residenza dei dati, controllo operativo e indipendenza della governance. Troppo spesso, le organizzazioni europee con i più elevati requisiti di sovranità sono bloccate a causa di offerte o ambienti on-premises legacy con funzionalità e servizi ridotti. In risposta a questa esigenza fondamentale, l’AWS European Sovereign Cloud rappresenta l’unico cloud sovrano con funzionalità complete e a gestione autonoma. supportato da solidi controlli tecnici, garanzie di sovranità e protezioni legali. Gli enti pubblici e le aziende di settori altamente regolamentati necessitano di un’infrastruttura cloud che fornisca controlli di sovranità avanzati che garantiscano l’innovazione, la sicurezza e l’affidabilità che si aspettano dai moderni servizi cloud. Queste organizzazioni devono essere certe che i propri dati e le proprie operazioni restino sotto la giurisdizione europea, con chiare strutture di governance e autonomia operativa nell’ambito dell’Unione europea (UE).

Una nuova infrastruttura cloud indipendente per l’Europa
L’AWS European Sovereign Cloud rappresenta un’infrastruttura cloud separata fisicamente e logicamente, con tutti i componenti situati interamente all’interno dell’UE. La prima Regione AWS nell’AWS European Sovereign Cloud, situata nello stato di Brandeburgo (Germania) e ora disponibile a livello generale, opera indipendentemente dalle Regioni AWS esistenti. L’infrastruttura presenta diverse zone di disponibilità con risorse di alimentazione e rete ridondanti, progettate per funzionare continuamente anche in caso di interruzione della connettività con il resto del mondo.

Abbiamo intenzione di estendere la presenza dell’AWS European Sovereign Cloud dalla Germania all’intera UE per supportare i rigorosi requisiti di isolamento, residenza dei dati all’interno di un determinato Paese e bassa latenza. Inizieremo con nuove zone locali sovrane situate in Belgio, nei Paesi Bassi e in Portogallo. Inoltre, sarà possibile estendere l’infrastruttura AWS European Sovereign Cloud con Zone locali AWS dedicate, AWS AI Factories o AWS Outposts in posizioni selezionate, inclusi i data center on-premises.

L’AWS European Sovereign Cloud e le relative zone locali forniscono controlli sovrani avanzati tramite un modello operativo esclusivo. L’AWS European Sovereign Cloud sarà gestito esclusivamente da residenti UE che si trovano nell’UE. Ciò copre attività come operazioni quotidiane, supporto tecnico e servizio clienti. Stiamo gradualmente trasformando l’AWS European Sovereign Cloud in modo che sia gestito esclusivamente da cittadini UE che si trovano nell’UE. Durante questo periodo di transizione, continueremo a lavorare con un team misto di residenti e cittadini comunitari che si trovano nell’UE.

L’infrastruttura è gestita da entità giuridiche europee dedicate, costituite secondo il diritto tedesco. Nell’ottobre 2025, AWS ha assegnato l’incarico di managing director a Stéphane Israël, cittadino comunitario residente nell’UE. Sarà responsabile della gestione e delle operazioni dell’AWS European Sovereign Cloud, inclusi infrastruttura, tecnologia e servizi, oltre a guidare le più ampie iniziative di sovranità digitale di AWS. Nel gennaio 2026, AWS ha inoltre nominato managing director dell’AWS European Sovereign Cloud Stefan Höchbauer (vicepresidente, Germania ed Europa centrale, AWS). Collaborerà con Stéphane Israël per guidare l’AWS European Sovereign Cloud.

Un comitato consultivo composto esclusivamente da cittadini comunitari, inclusi due rappresentanti terzi indipendenti, fornirà ulteriore supervisione e competenza in materia di sovranità.

Ottimizzazione del controllo e della residenza dei dati
L’AWS European Sovereign Cloud offre garanzie complete sulla residenza dei dati in modo da poter soddisfare i requisiti più rigorosi in materia. Come per le nostre Regioni AWS esistenti a livello mondiale, tutti i contenuti restano all’interno della Regione selezionata, a meno che non si scelga diversamente. Oltre ai contenuti, anche i metadati creati dai clienti, tra cui ruoli, autorizzazioni, etichette delle risorse e configurazioni, restano nell’ambito dell’UE. L’infrastruttura è dotata di un proprio sistema AWS Identity and Access Management (AWS IAM) e di fatturazione dedicato, completamente gestito in modo indipendente all’interno dei confini europei.

I controlli tecnici integrati nell’infrastruttura impediscono l’accesso all’AWS European Sovereign Cloud dall’esterno dell’UE. L’infrastruttura include un provider di servizi fiduciari europeo dedicato per le operazioni delle autorità di certificazione e utilizza nameserver Amazon Route 53 dedicati. Questi server utilizzeranno solo domini di primo livello (TLD) europei per i propri nomi. L’AWS European Sovereign Cloud non ha dipendenze fondamentali da personale o infrastrutture non UE.

Framework di sicurezza e conformità
L’AWS European Sovereign Cloud mantiene le stesse funzionalità di sicurezza di base di AWS, tra cui crittografia, gestione delle chiavi, governance degli accessi e AWS Nitro System per l’isolamento computazionale. Ciò significa che le istanze EC2 beneficiano dell’integrità della piattaforma verificata a livello di crittografia e dei limiti imposti dall’hardware che impediscono l’accesso non autorizzato ai dati senza compromettere le prestazioni, offrendo i controlli di sovranità e la potenza di calcolo richiesti dai carichi di lavoro. L’infrastruttura è sottoposta ad audit di terze parti indipendenti, con programmi di conformità che includono ISO/IEC 27001:2013, report SOC 1/2/3 e attestazione C5 dell’Ufficio Federale per la Sicurezza Informatica (BSI).

L’AWS European Sovereign Cloud: Sovereign Reference Framework definisce i controlli di sovranità specifici in termini di indipendenza della governance, controllo operativo, residenza dei dati e isolamento tecnico. Questo framework è disponibile in AWS Artifact e fornisce visibilità end-to-end tramite l’attestazione SOC 2.

Disponibilità completa del servizio
Dal momento del lancio, sarà possibile accedere a un’ampia gamma di servizi AWS nell’AWS European Sovereign Cloud, tra cui Amazon SageMaker e Amazon Bedrock per carichi di lavoro di intelligenza artificiale e machine learning (IA/ML). Per i calcoli, è possibile utilizzare Amazon Elastic Compute Cloud (Amazon EC2) e AWS Lambda. L’orchestrazione di container è disponibile tramite Amazon Elastic Kubernetes Service (Amazon EKS) e Amazon Elastic Container Service (Amazon ECS). I servizi di database includono Amazon Aurora, Amazon DynamoDB e Amazon Relational Database Service (Amazon RDS). Le opzioni di storage includono Amazon Simple Storage Service (Amazon S3) e Amazon Elastic Block Store (Amazon EBS), con connessione in rete tramite Amazon Virtual Private Cloud (Amazon VPC) e servizi di sicurezza tra cui Servizio AWS di gestione delle chiavi (AWS KMS) e Autorità di certificazione privata AWS (AWS Private CA). Per un elenco aggiornato dei servizi, è possibile consultare l’elenco delle funzionalità AWS pubblicato di recente su AWS Builder Center.

L’AWS European Sovereign Cloud è supportato dai partner AWS, che aiutano a soddisfare i propri requisiti di sovranità. Partner come Adobe, Cisco, Cloudera, Dedalus, Esri, Genesys, GitLab, Mendix, Pega, SAP, SnowFlake, Trend Micro e Wiz stanno rendendo disponibili le loro soluzioni nell’AWS European Sovereign Cloud, fornendo gli strumenti e i servizi necessari per la sicurezza, l’analisi dei dati, lo sviluppo di applicazioni e i carichi di lavoro specifici del settore. Questo ampio supporto dei partner aiuta a creare soluzioni sovrane che combinano i servizi AWS con tecnologie di partner affidabili.

Investimenti significativi nelle infrastrutture europee
L’AWS European Sovereign Cloud è sostenuto da un investimento di 7,8 miliardi di euro destinati a infrastrutture, creazione di posti di lavoro e sviluppo delle competenze. Si prevede che questo investimento contribuirà con 17,2 miliardi di euro all’economia europea fino al 2040 e sosterrà circa 2.800 posti di lavoro equivalenti a tempo pieno all’anno nelle aziende locali.

Alcuni dettagli tecnici
L’AWS European Sovereign Cloud è disponibile per tutti i clienti, indipendentemente da dove si trovino. È possibile accedere all’infrastruttura utilizzando il nome della partizione aws-eusc e il nome della Regione eusc-de-east-1. Una partizione è un gruppo di Regioni AWS. Ogni account AWS è associato a una partizione.

L’infrastruttura supporta tutti i metodi di accesso AWS standard, tra cui la Console di gestione AWS, gli SDK AWS e l’interfaccia della linea di comando AWS (AWS CLI), semplificando l’integrazione nell’automazione e nei flussi di lavoro esistenti. Dopo aver creato un nuovo account root per la partizione Di AWS European Sovereign Cloud, si inizia creando nuove identità e ruoli IAM specifici per questa infrastruttura, che consentiranno di avere il controllo completo sulla gestione degli accessi all’interno dell’ambiente sovrano europeo.

Nozioni di base
L’AWS European Sovereign Cloud fornisce alle organizzazioni europee controlli di sovranità avanzati pur mantenendo l’accesso all’innovazione e alle funzionalità di AWS. È possibile contrattare servizi tramite Amazon Web Services EMEA SARL, con prezzi in EUR e fatturazione in una delle otto valute supportate oggi. L’infrastruttura utilizza l’architettura AWS, il portafoglio di servizi e le API tradizionali, semplificando la creazione e la migrazione delle applicazioni.

L’addendum di AWS European Sovereign Cloud include gli impegni contrattuali aggiuntivi per l’AWS European Sovereign Cloud.

Per me come europeo, questo lancio rappresenta l’impegno di AWS per soddisfare le esigenze specifiche del nostro continente e fornire le funzionalità cloud che guidano l’innovazione in tutti i settori. Invito tutti a scoprire di più sull’AWS European Sovereign Cloud e su come può aiutare le organizzazioni a soddisfare i requisiti di sovranità. Nella Panoramica di AWS European Sovereign Cloud sono disponibili maggiori informazioni sugli obiettivi e sull’approccio di progettazione, creare un nuovo account  e pianificare l’implementazione del primo carico di lavoro oggi stesso.

— seb


Spanish version

Apertura de AWS European Sovereign Cloud

Como ciudadano europeo, comprendo de primera mano la importancia de la soberanía digital, especialmente para las organizaciones de nuestro sector público y las industrias altamente reguladas. Hoy me complace anunciar que la AWS European Sovereign Cloud ya está disponible de forma generalizada para todos los clientes. Anunciamos por primera vez nuestros planes de crear esta nueva infraestructura de nube independiente en 2023, y hoy está lista para cumplir los requisitos de soberanía más estrictos de los clientes europeos con un exhaustivo conjunto de servicios de AWS.

Berlín, Puerta de Brandeburgo al atardecer

Cumplimiento de los requisitos de soberanía europeos
Las organizaciones de toda Europa se enfrentan a unos requisitos normativos cada vez más complejos en relación con la residencia de los datos, el control operativo y la independencia de la gobernanza. Hoy en día, con demasiada frecuencia, las organizaciones europeas con los requisitos de soberanía más estrictos se ven atrapadas en entornos locales heredados u ofertas con servicios y funcionalidades reducidos. En respuesta a esta necesidad crítica, la AWS European Sovereign Cloud es la única nube soberana independiente con todas las características que está respaldada por sólidos controles técnicos, garantías de soberanía y protecciones legales. Las entidades del sector público y las empresas de industrias altamente reguladas necesitan una infraestructura en la nube que proporcione controles de soberanía mejorados que mantengan la innovación, la seguridad y la fiabilidad que se esperan de los servicios modernos en la nube. Estas organizaciones necesitan la garantía de que sus datos y operaciones permanecen bajo la jurisdicción europea, con estructuras de gobernanza claras y autonomía operativa dentro de la Unión Europea (UE).

Una nueva infraestructura de nube independiente para Europa
La AWS European Sovereign Cloud es una infraestructura de nube separada de manera física y lógica, en la que todos los componentes están ubicados íntegramente dentro de la UE. La primera región de AWS de la AWS European Sovereign Cloud se encuentra en el estado de Brandeburgo (Alemania) y ya está disponible para el público en general. Esta región opera de forma independiente de las regiones de AWS existentes. La infraestructura cuenta con varias zonas de disponibilidad con fuentes de alimenacion y redes redundantes, diseñadas para funcionar de forma continua incluso si se interrumpe la conectividad con el resto del mundo.

Tenemos previsto ampliar la presencia de la AWS European Sovereign Cloud de Alemania a toda la UE para cumplir los requisitos de aismlamiento estrictos, residencia de los datos dentro del país y baja latencia. Esto comenzará con nuevas zonas locales soberanas ubicadas en Bélgica, los Países Bajos y Portugal. Además, podrá ampliar la infraestructura de la AWS European Sovereign Cloud con zonas locales dedicadas de AWS, AWS AI Factories o AWS Outposts en las ubicaciones que elija, incluidos sus propios centros de datos locales.

La AWS European Sovereign Cloud y sus zonas locales proporcionan controles soberanos mejorados a través de su modelo operativo único. La AWS European Sovereign Cloud será operada exclusivamente por residentes de la UE ubicados en la UE. Abarca actividades como las operaciones diarias, la asistencia técnica y el servicio de atención al cliente. Estamos realizando una transición gradual de la AWS European Sovereign Cloud para que se opere exclusivamente por ciudadanos de la UE ubicados en la UE. Durante este período de transición, seguiremos trabajando con un equipo mixto de residentes de la UE y ciudadanos de la UE ubicados en la UE.

La infraestructura se administra a través de entidades jurídicas europeas especializadas constituidas en el marco de la legislación alemana. En octubre de 2025, AWS nombró director general a Stéphane Israël, ciudadano de la UE que reside en la UE. Stéphane será responsable de la administración y las operaciones de la AWS European Sovereign Cloud, lo que incluye la infraestructura, la tecnología y los servicios, además de liderar los esfuerzos más amplios de AWS en materia de soberanía digital. En enero de 2026, AWS también nombró a Stefan Hoechbauer (vicepresidente de AWS para Alemania y Europa Central) director general de la AWS European Sovereign Cloud. Stefan dirigirá la AWS European Sovereign Cloud junto con Stéphane Israël.

Un consejo consultivo compuesto exclusivamente por ciudadanos de la UE, que incluye a dos representantes independientes externos, proporciona supervisión y experiencia adicional en materia de soberanía.

Mejor control y residencia de datos
La AWS European Sovereign Cloud ofrece amplias garantías de residencia de datos para que pueda cumplir los requisitos más estrictos en materia de residencia de datos. Al igual que ocurre con nuestras regiones de AWS existentes en todo el mundo, todo el contenido permanece dentro la región que elija, a menos que decida lo contrario. Además del contenido, los metadatos creados por los clientes, incluidos los roles, los permisos, las etiquetas de recursos y las configuraciones, también permanecen dentro de la UE. La infraestructura cuenta con su propio sistema dedicado de AWS Identity and Access Management (AWS IAM) y facturación, que funciona de forma independiente dentro de las fronteras europeas.

Los controles técnicos integrados en la infraestructura impiden el acceso a la AWS European Sovereign Cloud desde fuera de la UE. La infraestructura incluye un proveedor de servicios de confianza europeo dedicado para las operaciones de las autoridades de certificación y utiliza servidores de nombres de Amazon Route 53 dedicados. Estos servidores solo usarán dominios de nivel superior europeos para sus propios nombres. La AWS European Sovereign Cloud no tiene dependencias críticas de personal o infraestructura fuera de la UE.

Marco de seguridad y cumplimiento
La AWS European Sovereign Cloud mantiene las mismas capacidades de seguridad básicas que cabe esperar de AWS, como el cifrado, la administración de claves, la gobernanza del acceso y AWS Nitro System para el aislamiento de la computación. Esto significa que sus instancias de EC2 se benefician de la integridad de la plataforma verificada criptográficamente y de los límites impuestos por el hardware que impiden el acceso no autorizado a sus datos sin comprometer el rendimiento, lo que le proporciona tanto los controles de soberanía como la potencia computacional que requieren sus cargas de trabajo. La infraestructura se somete a auditorías independientes externas, con programas de cumplimiento que incluyen la norma ISO/IEC 27001:2013, informes SOC 1/2/3 y la certificación C5 de la Oficina Federal de Seguridad de la Información.

El marco de referencia de soberanía de la AWS European Sovereign Cloud define los controles de soberanía específicos en relación con la independencia de la gobernanza, el control operativo, la residencia de datos y el aislamiento técnico. Este marco está disponible en AWS Artifact y proporciona visibilidad total a través de la certificación SOC 2.

Disponibilidad total del servicio
Puede acceder a una amplia variedad de servicios de AWS en la AWS European Sovereign Cloud desde su lanzamiento, incluidos Amazon SageMaker y Amazon Bedrock para cargas de trabajo de inteligencia artificial y machine learning. Para el procesamiento, puede usar Amazon Elastic Compute Cloud (Amazon EC2) y AWS Lambda. La orquestación de contenedores está disponible a través de Amazon Elastic Kubernetes Service (Amazon EKS) y Amazon Elastic Container Service (Amazon ECS). Los servicios de bases de datos incluyen Amazon Aurora, Amazon DynamoDB y Amazon Relational Database Service (Amazon RDS). Dispone de opciones de almacenamiento como Amazon Simple Storage Service (Amazon S3) y Amazon Elastic Block Store (Amazon EBS), con redes a través de Amazon Virtual Private Cloud (Amazon VPC) y servicios de seguridad como AWS Key Management Service (AWS KMS) y AWS Private Certificate Authority. Para obtener una lista actualizada de los servicios, consulte la matriz de capacidades de AWS que se ha publicado recientemente en AWS Builder Center.

La AWS European Sovereign Cloud cuenta con el respaldo de los socios de AWS, que se comprometen a ayudarle a cumplir sus requisitos de soberanía. Socios como Adobe, Cisco, Cloudera, Dedalus, Esri, Genesys, GitLab, Mendix, Pega, SAP, SnowFlake, Trend Micro y Wiz ofrecen sus soluciones en la AWS European Sovereign Cloud, lo que le proporciona las herramientas y los servicios que necesita en materia de seguridad, análisis de datos, desarrollo de aplicaciones y cargas de trabajo específicas del sector. Este amplio apoyo de los socios le ayuda a crear soluciones soberanas que combinan los servicios de AWS con tecnologías de socios de confianza.

Inversión importante. en la infraestructura europea
La AWS European Sovereign Cloud está respaldada por una inversión de 7.800 millones de EUR en infraestructura, creación de empleo y desarrollo de habilidades. Se espera que esta inversión aporte 17.200 millones de EUR a la economía europea para 2040 y ayude a crear el equivalente a aproximadamente 2.800 puestos de trabajo a tiempo completo por año en empresas locales.

Algunos detalles técnicos
La AWS European Sovereign Cloud está disponible para todos los clientes, independientemente de dónde se encuentren. Puede acceder a la infraestructura utilizando el nombre de partición aws-eusc y el nombre de región eusc-de-east-1. Una partición es un grupo de regiones de AWS. Cada cuenta de AWS tiene limitado su alcance a una sola partición.

La infraestructura admite todos los métodos de acceso estándar de AWS, como la Consola de administración de AWS, los AWS SDK y la Interfaz de la línea de comandos de AWS (AWS CLI), lo que facilita la integración en sus flujos de trabajo y automatización existentes. Tras crear una nueva cuenta raíz para la partición de la AWS European Sovereign Cloud, primero deberá crear nuevas identidades y roles de IAM específicos para esta infraestructura, lo que le permitirá tener un control total sobre la administración del acceso en el entorno soberano europeo.

Cómo empezar
La AWS European Sovereign Cloud proporciona a las organizaciones europeas controles de soberanía mejorados, al tiempo que mantiene el acceso a la innovación y las capacidades de AWS. Puede contratar los servicios a través de Amazon Web Services EMEA SARL, con precios en EUR y facturación en cualquiera de las ocho divisas que admitimos actualmente. La infraestructura utiliza la arquitectura, la cartera de servicios y las API habituales de AWS, lo que facilita la creación y la migración de aplicaciones.

La adenda de la AWS European Sovereign Cloud contiene los compromisos contractuales adicionales para la AWS European Sovereign Cloud.

Para mí, como europeo, este lanzamiento representa el compromiso de AWS de satisfacer las necesidades específicas de nuestro continente y proporcionar las capacidades en la nube que impulsan la innovación en todos los sectores. Le invito a descubrir más sobre la AWS European Sovereign Cloud y cómo puede ayudar a su organización a cumplir sus requisitos de soberanía. Lea la descripción general de la AWS European Sovereign Cloud para obtener más información sobre los objetivos y el enfoque del diseño, regístrese para obtener una nueva cuenta y planifique hoy mismo el despliegue de su primera carga de trabajo.

— seb
Announcing replication support and Intelligent-Tiering for Amazon S3 Tables

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/announcing-replication-support-and-intelligent-tiering-for-amazon-s3-tables/

Today, we’re announcing two new capabilities for Amazon S3 Tables: support for the new Intelligent-Tiering storage class that automatically optimizes costs based on access patterns, and replication support to automatically maintain consistent Apache Iceberg table replicas across AWS Regions and accounts without manual sync.

Organizations working with tabular data face two common challenges. First, they need to manually manage storage costs as their datasets grow and access patterns change over time. Second, when maintaining replicas of Iceberg tables across Regions or accounts, they must build and maintain complex architectures to track updates, manage object replication, and handle metadata transformations.

S3 Tables Intelligent-Tiering storage class
With the S3 Tables Intelligent-Tiering storage class, data is automatically tiered to the most cost-effective access tier based on access patterns. Data is stored in three low-latency tiers: Frequent Access, Infrequent Access (40% lower cost than Frequent Access), and Archive Instant Access (68% lower cost compared to Infrequent Access). After 30 days without access, data moves to Infrequent Access, and after 90 days, it moves to Archive Instant Access. This happens without changes to your applications or impact on performance.

Table maintenance activities, including compaction, snapshot expiration, and unreferenced file removal, operate without affecting the data’s access tiers. Compaction automatically processes only data in the Frequent Access tier, optimizing performance for actively queried data while reducing maintenance costs by skipping colder files in lower-cost tiers.

By default, all existing tables use the Standard storage class. When creating new tables, you can specify Intelligent-Tiering as the storage class, or you can rely on the default storage class configured at the table bucket level. You can set Intelligent-Tiering as the default storage class for your table bucket to automatically store tables in Intelligent-Tiering when no storage class is specified during creation.

Let me show you how it works
You can use the AWS Command Line Interface (AWS CLI) and the put-table-bucket-storage-class and get-table-bucket-storage-class commands to change or verify the storage tier of your S3 table bucket.

# Change the storage class
aws s3tables put-table-bucket-storage-class \
   --table-bucket-arn $TABLE_BUCKET_ARN  \
   --storage-class-configuration storageClass=INTELLIGENT_TIERING

# Verify the storage class
aws s3tables get-table-bucket-storage-class \
   --table-bucket-arn $TABLE_BUCKET_ARN  \

{ "storageClassConfiguration":
   { 
      "storageClass": "INTELLIGENT_TIERING"
   }
}

S3 Tables replication support
The new S3 Tables replication support helps you maintain consistent read replicas of your tables across AWS Regions and accounts. You specify the destination table bucket and the service creates read-only replica tables. It replicates all updates chronologically while preserving parent-child snapshot relationships. Table replication helps you build global datasets to minimize query latency for geographically distributed teams, meet compliance requirements, and provide data protection.

You can now easily create replica tables that deliver similar query performance as their source tables. Replica tables are updated within minutes of source table updates and support independent encryption and retention policies from their source tables. Replica tables can be queried using Amazon SageMaker Unified Studio or any Iceberg-compatible engine including DuckDB, PyIceberg, Apache Spark, and Trino.

You can create and maintain replicas of your tables through the AWS Management Console or APIs and AWS SDKs. You specify one or more destination table buckets to replicate your source tables. When you turn on replication, S3 Tables automatically creates read-only replica tables in your destination table buckets, backfills them with the latest state of the source table, and continually monitors for new updates to keep replicas in sync. This helps you meet time-travel and audit requirements while maintaining multiple replicas of your data.

Let me show you how it works
To show you how it works, I proceed in three steps. First, I create an S3 table bucket, create an Iceberg table, and populate it with data. Second, I configure the replication. Third, I connect to the replicated table and query the data to show you that changes are replicated.

For this demo, the S3 team kindly gave me access to an Amazon EMR cluster already provisioned. You can follow the Amazon EMR documentation to create your own cluster. They also created two S3 table buckets, a source and a destination for the replication. Again, the S3 Tables documentation will help you to get started.

I take a note of the two S3 Tables bucket Amazon Resource Names (ARNs). In this demo, I refer to these as the environment variables SOURCE_TABLE_ARN and DEST_TABLE_ARN.

First step: Prepare the source database

I start a terminal, connect to the EMR cluster, start a Spark session, create a table, and insert a row of data. The commands I use in this demo are documented in Accessing tables using the Amazon S3 Tables Iceberg REST endpoint.

sudo spark-shell \
--packages "org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.4.1,software.amazon.awssdk:bundle:2.20.160,software.amazon.awssdk:url-connection-client:2.20.160" \
--master "local[*]" \
--conf "spark.sql.extensions=org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions" \
--conf "spark.sql.defaultCatalog=spark_catalog" \
--conf "spark.sql.catalog.spark_catalog=org.apache.iceberg.spark.SparkCatalog" \
--conf "spark.sql.catalog.spark_catalog.type=rest" \
--conf "spark.sql.catalog.spark_catalog.uri=https://s3tables.us-east-1.amazonaws.com/iceberg" \
--conf "spark.sql.catalog.spark_catalog.warehouse=arn:aws:s3tables:us-east-1:012345678901:bucket/aws-news-blog-test" \
--conf "spark.sql.catalog.spark_catalog.rest.sigv4-enabled=true" \
--conf "spark.sql.catalog.spark_catalog.rest.signing-name=s3tables" \
--conf "spark.sql.catalog.spark_catalog.rest.signing-region=us-east-1" \
--conf "spark.sql.catalog.spark_catalog.io-impl=org.apache.iceberg.aws.s3.S3FileIO" \
--conf "spark.hadoop.fs.s3a.aws.credentials.provider=org.apache.hadoop.fs.s3a.SimpleAWSCredentialProvider" \
--conf "spark.sql.catalog.spark_catalog.rest-metrics-reporting-enabled=false"

spark.sql("""
CREATE TABLE s3tablesbucket.test.aws_news_blog (
customer_id STRING,
address STRING
) USING iceberg
""")

spark.sql("INSERT INTO s3tablesbucket.test.aws_news_blog VALUES ('cust1', 'val1')")

spark.sql("SELECT * FROM s3tablesbucket.test.aws_news_blog LIMIT 10").show()
+-----------+-------+
|customer_id|address|
+-----------+-------+
|      cust1|   val1|
+-----------+-------+

So far, so good.

Second step: Configure the replication for S3 Tables

Now, I use the CLI on my laptop to configure the S3 table bucket replication.

Before doing so, I create an AWS Identity and Access Management (IAM) policy to authorize the replication service to access my S3 table bucket and encryption keys. Refer to the S3 Tables replication documentation for the details. The permissions I used for this demo are:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "s3:*",
                "s3tables:*",
                "kms:DescribeKey",
                "kms:GenerateDataKey",
                "kms:Decrypt"
            ],
            "Resource": "*"
        }
    ]
}

After having created this IAM policy, I can now proceed and configure the replication:

aws s3tables-replication put-table-replication \
--table-arn ${SOURCE_TABLE_ARN} \
--configuration  '{
    "role": "arn:aws:iam::<MY_ACCOUNT_NUMBER>:role/S3TableReplicationManualTestingRole", 
    "rules":[
        {
            "destinations": [
                {
                    "destinationTableBucketARN": "${DST_TABLE_ARN}"
                }]
        }
    ]

The replication starts automatically. Updates are typically replicated within minutes. The time it takes to complete depends on the volume of data in the source table.

Third step: Connect to the replicated table and query the data

Now, I connect to the EMR cluster again, and I start a second Spark session. This time, I use the destination table.

S3 Tables replication - destination table

To verify the replication works, I insert a second row of data on the source table.

spark.sql("INSERT INTO s3tablesbucket.test.aws_news_blog VALUES ('cust2', 'val2')")

I wait a few minutes for the replication to trigger. I follow the status of the replication with the get-table-replication-status command.

aws s3tables-replication get-table-replication-status \
--table-arn ${SOURCE_TABLE_ARN} \
{
    "sourceTableArn": "arn:aws:s3tables:us-east-1:012345678901:bucket/manual-test/table/e0fce724-b758-4ee6-85f7-ca8bce556b41",
    "destinations": [
        {
            "replicationStatus": "pending",
            "destinationTableBucketArn": "arn:aws:s3tables:us-east-1:012345678901:bucket/manual-test-dst",
            "destinationTableArn": "arn:aws:s3tables:us-east-1:012345678901:bucket/manual-test-dst/table/5e3fb799-10dc-470d-a380-1a16d6716db0",
            "lastSuccessfulReplicatedUpdate": {
                "metadataLocation": "s3://e0fce724-b758-4ee6-8-i9tkzok34kum8fy6jpex5jn68cwf4use1b-s3alias/e0fce724-b758-4ee6-85f7-ca8bce556b41/metadata/00001-40a15eb3-d72d-43fe-a1cf-84b4b3934e4c.metadata.json",
                "timestamp": "2025-11-14T12:58:18.140281+00:00"
            }
        }
    ]
}

When replication status shows ready, I connect to the EMR cluster and I query the destination table. Without surprise, I see the new row of data.

S3 Tables replication - target table is up to date

Additional things to know
Here are a couple of additional points to pay attention to:

  • Replication for S3 Tables supports both Apache Iceberg V2 and V3 table formats, giving you flexibility in your table format choice.
  • You can configure replication at the table bucket level, making it straightforward to replicate all tables under that bucket without individual table configurations.
  • Your replica tables maintain the storage class you choose for your destination tables, which means you can optimize for your specific cost and performance needs.
  • Any Iceberg-compatible catalog can directly query your replica tables without additional coordination—they only need to point to the replica table location. This gives you flexibility in choosing query engines and tools.

Pricing and availability
You can track your storage usage by access tier through AWS Cost and Usage Reports and Amazon CloudWatch metrics. For replication monitoring, AWS CloudTrail logs provide events for each replicated object.

There are no additional charges to configure Intelligent-Tiering. You only pay for storage costs in each tier. Your tables continue to work as before, with automatic cost optimization based on your access patterns.

For S3 Tables replication, you pay the S3 Tables charges for storage in the destination table, for replication PUT requests, for table updates (commits), and for object monitoring on the replicated data. For cross-Region table replication, you also pay for inter-Region data transfer out from Amazon S3 to the destination Region based on the Region pair.

As usual, refer to the Amazon S3 pricing page for the details.

Both capabilities are available today in all AWS Regions where S3 Tables are supported.

To learn more about these new capabilities, visit the Amazon S3 Tables documentation or try them in the Amazon S3 console today. Share your feedback through AWS re:Post for Amazon S3 or through your AWS Support contacts.

— seb

Amazon S3 Vectors now generally available with increased scale and performance

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/amazon-s3-vectors-now-generally-available-with-increased-scale-and-performance/

Today, I’m excited to announce that Amazon S3 Vectors is now generally available with significantly increased scale and production-grade performance capabilities. S3 Vectors is the first cloud object storage with native support to store and query vector data. You can use it to help you reduce the total cost of storing and querying vectors by up to 90% when compared to specialized vector database solutions.

Since we announced the preview of S3 Vectors in July, I’ve been impressed by how quickly you adopted this new capability to store and query vector data. In just over four months, you created over 250,000 vector indexes and ingested more than 40 billion vectors, performing over 1 billion queries (as of November 28th).

You can now store and search across up to 2 billion vectors in a single index, that’s up to 20 trillion vectors in a vector bucket and a 40x increase from 50 million per index during preview. This means that you can consolidate your entire vector dataset into one index, removing the need to shard across multiple smaller indexes or implement complex query federation logic.

Query performance has been optimized. Infrequent queries continue to return results in under one second, with more frequent queries now resulting in latencies around 100ms or less, making it well-suited for interactive applications such as conversational AI and multi-agent workflows. You can also retrieve up to 100 search results per query, up from 30 previously, providing more comprehensive context for retrieval augmented generation (RAG) applications.

The write performance has also improved substantially, with support for up to 1,000 PUT transactions per second when streaming single-vector updates into your indexes, delivering significantly higher write throughput for small batch sizes. This higher throughput supports workloads where new data must be immediately searchable, helping you ingest small data corpora quickly or handle many concurrent sources writing simultaneously to the same index.

The fully serverless architecture removes infrastructure overhead—there’s no infrastructure to set up or resources to provision. You pay for what you use as you store and query vectors. This AI-ready storage provides you with quick access to any amount of vector data to support your complete AI development lifecycle, from initial experimentation and prototyping through to large-scale production deployments. S3 Vectors now provides the scale and performance needed for production workloads across AI agents, inference, semantic search, and RAG applications.

Two key integrations that were launched in preview are now generally available. You can use S3 Vectors as a vector storage engine for Amazon Bedrock Knowledge Base. In particular, you can use it to build RAG applications with production-grade scale and performance. Moreover, S3 Vectors integration with Amazon OpenSearch is now generally available, so that you can use S3 Vectors as your vector storage layer while using OpenSearch for search and analytics capabilities.

You can now use S3 Vectors in 14 AWS Regions, expanding from five AWS Regions during the preview.

Let’s see how it works
In this post, I demonstrate how to use S3 Vectors through the AWS Console and CLI.

First, I create an S3 Vector bucket and an index.

echo "Creating S3 Vector bucket..."
aws s3vectors create-vector-bucket \
    --vector-bucket-name "$BUCKET_NAME"

echo "Creating vector index..."
aws s3vectors create-index \
    --vector-bucket-name "$BUCKET_NAME" \
    --index-name "$INDEX_NAME" \
    --data-type "float32" \
    --dimension "$DIMENSIONS" \
    --distance-metric "$DISTANCE_METRIC" \
    --metadata-configuration "nonFilterableMetadataKeys=AMAZON_BEDROCK_TEXT,AMAZON_BEDROCK_METADATA"

The dimension metric must match the dimension of the model used to compute the vectors. The distance metric indicates to the algorithm to compute the distance between vectors. S3 Vectors supports cosine and euclidian distances.

I can also use the console to create the bucket. We’ve added the capability to configure encryption parameters at creation time. By default, indexes use the bucket-level encryption, but I can override bucket-level encryption at the index level with a custom AWS Key Management Service (AWS KMS) key.

I also can add tags for the vector bucket and vector index. Tags at the vector index help with access control and cost allocation.

S3 Vector console - create

And I can now manage Properties and Permissions directly in the console.

S3 Vector console - properties

S3 Vector console - create

Similarly, I define Non-filterable metadata and I configure Encryption parameters for the vector index.

S3 Vector console - create index

Next, I create and store the embeddings (vectors). For this demo, I ingest my constant companion: the AWS Style Guide. This is an 800-page document that describes how to write posts, technical documentation, and articles at AWS.

I use Amazon Bedrock Knowledge Bases to ingest the PDF document stored on a general purpose S3 bucket. Amazon Bedrock Knowledge Bases reads the document and splits it in pieces called chunks. Then, it computes the embeddings for each chunk with the Amazon Titan Text Embeddings model and it stores the vectors and their metadata on my newly created vector bucket. The detailed steps for that process are out of the scope of this post, but you can read the instructions in the documentation.

When querying vectors, you can store up to 50 metadata keys per vector, with up to 10 marked as non-filterable. You can use the filterable metadata keys to filter query results based on specific attributes. Therefore, you can combine vector similarity search with metadata conditions to narrow down results. You can also store more non-filterable metadata for larger contextual information. Amazon Bedrock Knowledge Bases computes and stores the vectors. It also adds large metadata (the chunk of the original text). I exclude this metadata from the searchable index.

There are other methods to ingest your vectors. You can try the S3 Vectors Embed CLI, a command line tool that helps you generate embeddings using Amazon Bedrock and store them in S3 Vectors through direct commands. You can also use S3 Vectors as a vector storage engine for OpenSearch.

Now I’m ready to query my vector index. Let’s imagine I wonder how to write “open source”. Is it “open-source”, with a hyphen, or “open source” without a hyphen? Should I use uppercase or not? I want to search the relevant sections of the AWS Style Guide relative to “open source.”

# 1. Create embedding request
echo '{"inputText":"Should I write open source or open-source"}' | base64 | tr -d '\n' > body_encoded.txt

# 2. Compute the embeddings with Amazon Titan Embed model
aws bedrock-runtime invoke-model \
  --model-id amazon.titan-embed-text-v2:0 \
  --body "$(cat body_encoded.txt)" \
  embedding.json

# Search the S3 Vectors index for similar chunks
vector_array=$(cat embedding.json | jq '.embedding') && \
aws s3vectors query-vectors \
  --index-arn "$S3_VECTOR_INDEX_ARN" \
  --query-vector "{\"float32\": $vector_array}" \
  --top-k 3 \
  --return-metadata \
  --return-distance | jq -r '.vectors[] | "Distance: \(.distance) | Source: \(.metadata."x-amz-bedrock-kb-source-uri" | split("/")[-1]) | Text: \(.metadata.AMAZON_BEDROCK_TEXT[0:100])..."'

The first result shows this JSON:

        {
            "key": "348e0113-4521-4982-aecd-0ee786fa4d1d",
            "metadata": {
                "x-amz-bedrock-kb-data-source-id": "0SZY6GYPVS",
                "x-amz-bedrock-kb-source-uri": "s3://sst-aws-docs/awsstyleguide.pdf",
                "AMAZON_BEDROCK_METADATA": "{\"createDate\":\"2025-10-21T07:49:38Z\",\"modifiedDate\":\"2025-10-23T17:41:58Z\",\"source\":{\"sourceLocation\":\"s3://sst-aws-docs/awsstyleguide.pdf\"",
                "AMAZON_BEDROCK_TEXT": "[redacted] open source (adj., n.) Two words. Use open source as an adjective (for example, open source software), or as a noun (for example, the code throughout this tutorial is open source). Don't use open-source, opensource, or OpenSource. [redacted]",
                "x-amz-bedrock-kb-document-page-number": 98.0
            },
            "distance": 0.63120436668396
        }

It finds the relevant section in the AWS Style Guide. I must write “open source” without a hyphen. It even retrieved the page number in the original document to help me cross-check the suggestion with the relevant paragraph in the source document.

One more thing
S3 Vectors has also expanded its integration capabilities. You can now use AWS CloudFormation to deploy and manage your vector resources, AWS PrivateLink for private network connectivity, and resource tagging for cost allocation and access control.

Pricing and availability
S3 Vectors is now available in 14 AWS Regions, adding Asia Pacific (Mumbai, Seoul, Singapore, Tokyo), Canada (Central), and Europe (Ireland, London, Paris, Stockholm) to the existing five Regions from preview (US East (Ohio, N. Virginia), US West (Oregon), Asia Pacific (Sydney), and Europe (Frankfurt))

Amazon S3 Vectors pricing is based on three dimensions. PUT pricing is calculated based on the logical GB of vectors you upload, where each vector includes its logical vector data, metadata, and key. Storage costs are determined by the total logical storage across your indexes. Query charges include a per-API charge plus a $/TB charge based on your index size (excluding non-filterable metadata). As your index scales beyond 100,000 vectors, you benefit from lower $/TB pricing. As usual, the Amazon S3 pricing page has the details.

To get started with S3 Vectors, visit the Amazon S3 console. You can create vector indexes, start storing your embeddings, and begin building scalable AI applications. For more information, check out the Amazon S3 User Guide or the AWS CLI Command Reference.

I look forward to seeing what you build with these new capabilities. Please share your feedback through AWS re:Post or your usual AWS Support contacts.

— seb

AWS DevOps Agent helps you accelerate incident response and improve system reliability (preview)

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-devops-agent-helps-you-accelerate-incident-response-and-improve-system-reliability-preview/

Today, we’re announcing the public preview of AWS DevOps Agent, a frontier agent that helps you respond to incidents, identify root causes, and prevent future issues through systematic analysis of past incidents and operational patterns.

Frontier agents represent a new class of AI agents that are autonomous, massively scalable, and work for hours or days without constant intervention.

When production incidents occur, on-call engineers face significant pressure to quickly identify root causes while managing stakeholder communications. They must analyze data across multiple monitoring tools, review recent deployments, and coordinate response teams. After service restoration, teams often lack bandwidth to transform incident learnings into systematic improvements.

AWS DevOps Agent is your always-on, autonomous on-call engineer. When issues arise, it automatically correlates data across your operational toolchain, from metrics and logs to recent code deployments in GitHub or GitLab. It identifies probable root causes and recommends targeted mitigations, helping reduce mean time to resolution. The agent also manages incident coordination, using Slack channels for stakeholder updates and maintaining detailed investigation timelines.

To get started, you connect AWS DevOps Agent to your existing tools through the AWS Management Console. The agent works with popular services such as Amazon CloudWatch, Datadog, Dynatrace, New Relic, and Splunk for observability data, while integrating with GitHub Actions and GitLab CI/CD to track deployments and their impact on your cloud resources. Through the bring your own (BYO) Model Context Protocol (MCP) server capability, you can also integrate additional tools such as your organization’s custom tools, specialized platforms or open source observability solutions, such as Grafana and Prometheus into your investigations.

The agent acts as a virtual team member and can be configured to automatically respond to incidents from your ticketing systems. It includes built-in support for ServiceNow, and through configurable webhooks, can respond to events from other incident management tools like PagerDuty. As investigations progress, the agent updates tickets and relevant Slack channels with its findings. All of this is powered by an intelligent application topology the agent builds—a comprehensive map of your system components and their interactions, including deployment history that helps identify potential deployment-related causes during investigations.

Let me show you how it works
To show you how it works, I deployed a straigthforward AWS Lambda function that intentionally generates errors when invoked. I deployed it in an AWS CloudFormation stack.

Step 1: Create an Agent Space

An Agent Space defines the scope of what AWS DevOps Agent can access as it performs tasks.

You can organize Agent Spaces based on your operational model. Some teams align an Agent Space with a single application, others create one per on-call team managing multiple services, and some organizations use a centralized approach. For this demonstration, I’ll show you how to create an Agent Space for a single application. This setup helps isolate investigations and resources for that specific application, making it easier to track and analyze incidents within its context.

In the AWS DevOps Agent section of the AWS Management Console, I select Create Agent Space, enter a name for this space and create the AWS Identity and Access Management (IAM) roles it uses to introspect AWS resources in my or others’ AWS accounts.

AWS DevOps Agent - Create an Agent SpaceFor this demo, I choose to enable the AWS DevOps Agent web app; more about this later. This can be done at a later stage.

When ready, I choose Create.

AWS DevOps Agent - Enable Web AppAfter it has been created, I choose the Topology tab.

This view shows the key resources, entities, and relationships AWS DevOps Agent has selected as a foundation for performing its tasks efficiently. It doesn’t represent everything AWS DevOps Agent can access or see, only what the Agent considers most relevant right now. By default, the Topology includes the AWS resources that are contained in my account. As your agent completes more tasks, it will discover and add new resources to this list.

AWS DevOps Agent - Topology

Step 2: Configure the AWS DevOps web app for the operators

The AWS DevOps Agent web app provides a web interface for on-call engineers to manually trigger investigations, view investigation details including relevant topology elements, steer investigations, and ask questions about an investigation.

I can access the web app directly from my Agent Space in the AWS console by choosing the Operator access link. Alternatively, I can use AWS IAM Identity Center to configure user access for my team. IAM Identity Center lets me manage users and groups directly or connect to an identity provider (IdP), providing a centralized way to control who can access the AWS DevOps Agent web app.

AWS DevOps Agent - web app access

At this stage, I have an Agent Space all set up to focus investigations and resources for this specific application, and I’ve enabled the DevOps team to initiate investigations using the web app.

Now that the one-time setup for this application is done, I start invoking the faulty Lambda function. It generates errors at each invocation. The CloudWatch alarm associated with the Lambda errors count turns on to ALARM state. In real life, you might receive an alert from external services, such as ServiceNow. You can configure AWS DevOps Agent to automatically start investigations when receiving such alerts.

For this demo, I manually start the investigation by selecting Start Investigation.

You can also choose from several preconfigured starting points to quickly begin your investigation: Latest alarm to investigate your most recent triggered alarm and analyze the underlying metrics and logs to determine the root cause, High CPU usage to investigate high CPU utilization metrics across your compute resources and identify which processes or services are consuming excessive resources, or Error rate spike to investigate the recent increase in application error rates by analyzing metrics, application logs, and identifying the source of failures.

AWS DevOps Agent - web app

I enter some information, such as Investigation details, Investigation starting point, the Date and time of the incident, the AWS Account ID for the incident.

- web app - start investigation

In the AWS DevOps Agent web app, you can watch the investigation unfold in real time. The agent identifies the application stack. It correlates metrics from CloudWatch, examines logs from CloudWatch Logs or external sources, such as Splunk, reviews recent code changes from GitHub, and analyzes traces from AWS X-Ray.

- web app - application stack

It identifies the error patterns and provides a detailed investigation summary. In the context of this demo, the investigation reveals that these are intentional test exceptions, shows the timeline of function invocations leading to the alarm, and even suggests monitoring improvements for error handling.
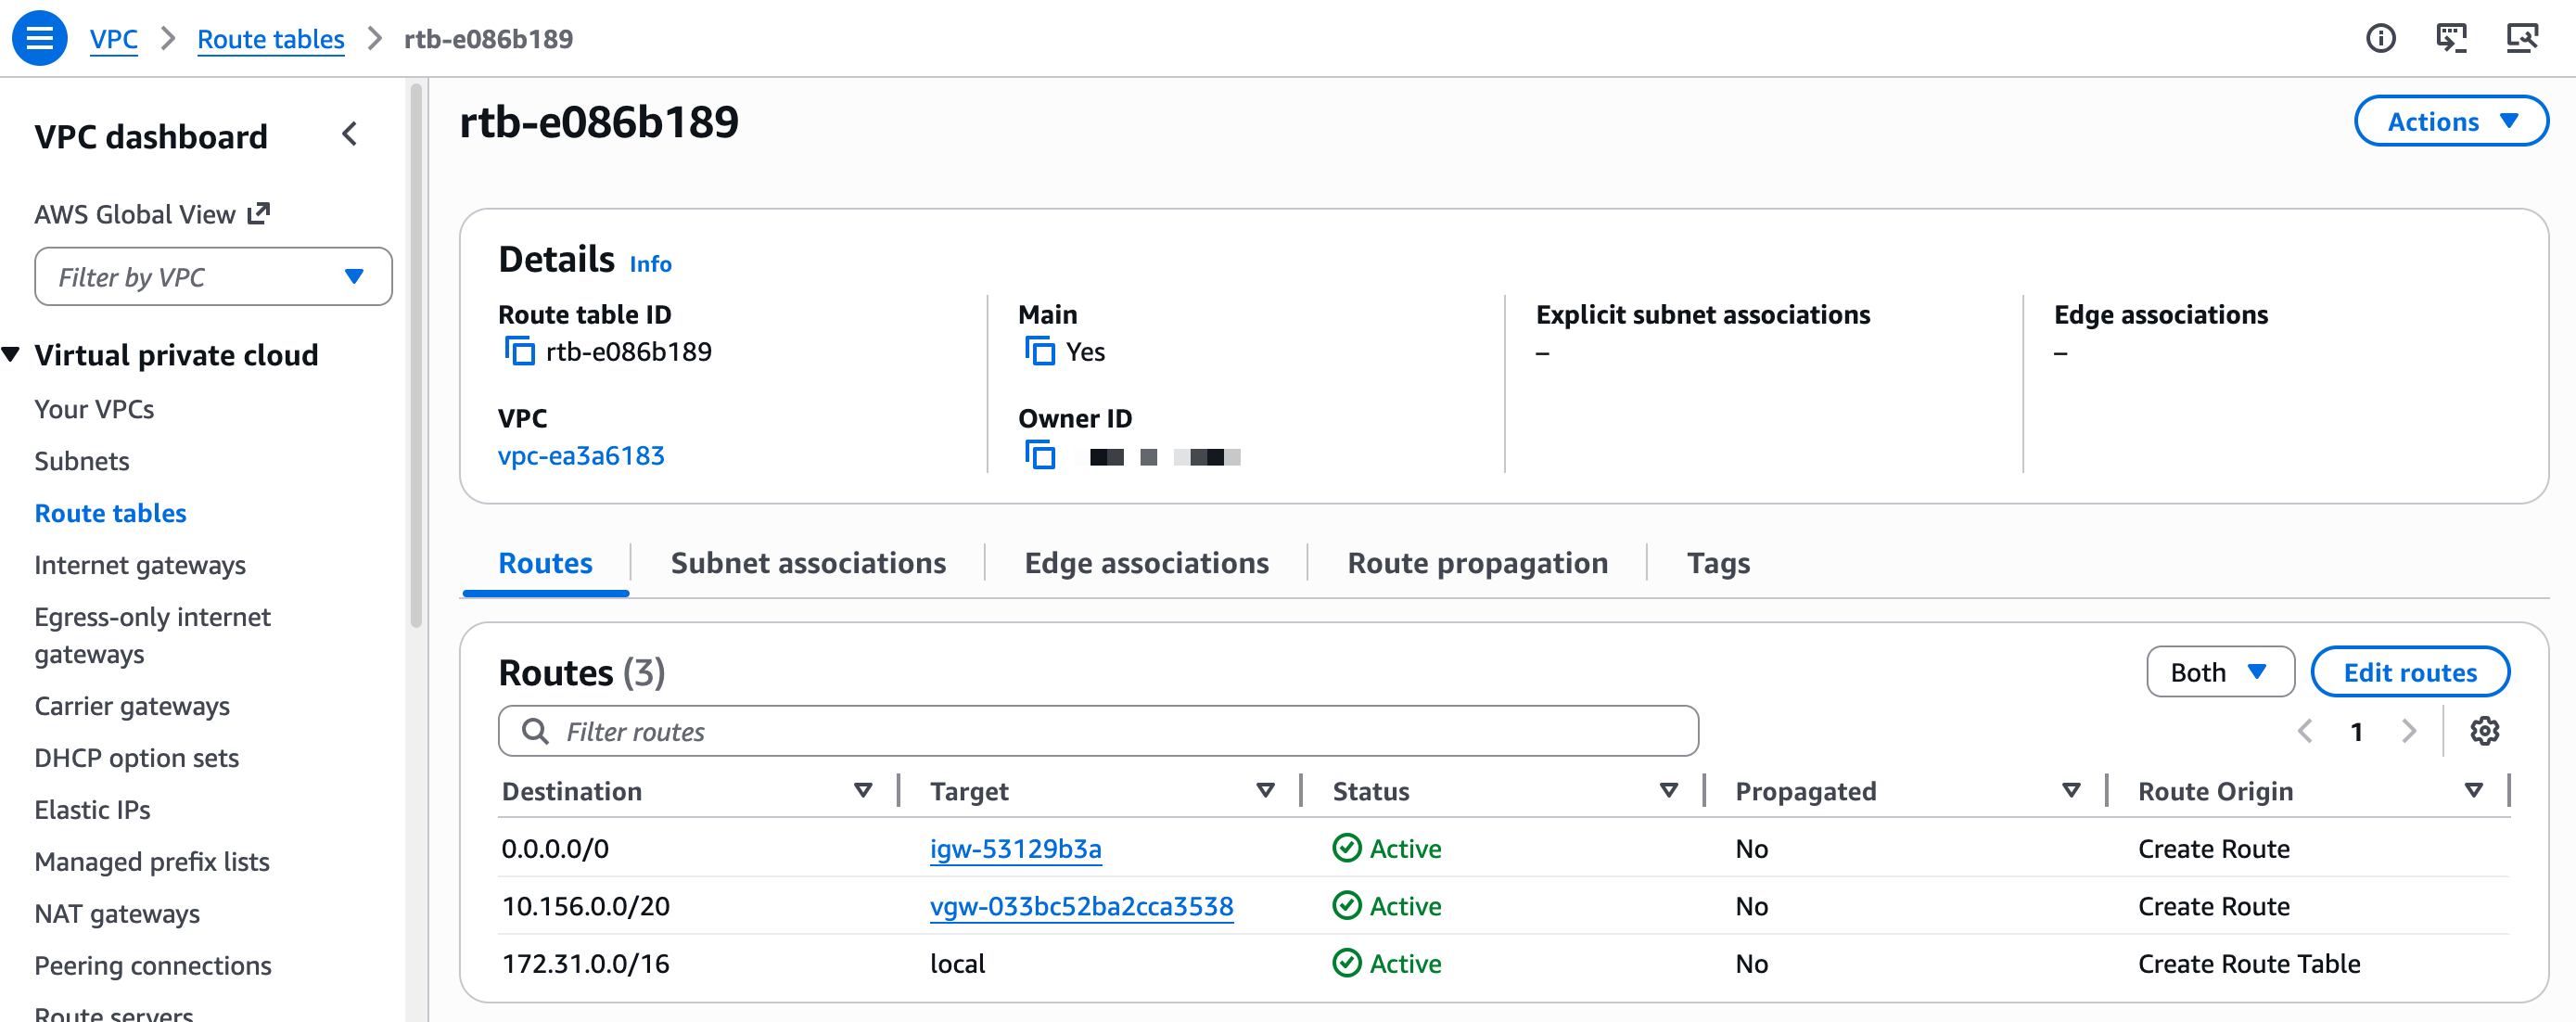
The agent uses a dedicated incident channel in Slack, notifies on-call teams if needed, and provides real-time status updates to stakeholders. Through the investigation chat interface, you can interact directly with the agent by asking clarifying questions such as “which logs did you analyze?” or steering the investigation by providing additional context, such as “focus on these specific log groups and rerun your analysis.” If you need expert assistance, you can create an AWS Support case with a single click, automatically populating it with the agent’s findings, and engage with AWS Support experts directly through the investigation chat window.

For this demo, the AWS DevOps Agent correctly identified manual activities in the Lambda console to invoke a function that intentionally triggers errors 😇.

- web app - root cause

Beyond incident response, AWS DevOps Agent analyzes my recent incidents to identify high-impact improvements that prevent future issues.

During active incidents, the agent offers immediate mitigation plans through its incident mitigations tab to help restore service quickly. Mitigation plans consist of specs that provide detailed implementation guidance for developers and agentic development tools like Kiro.
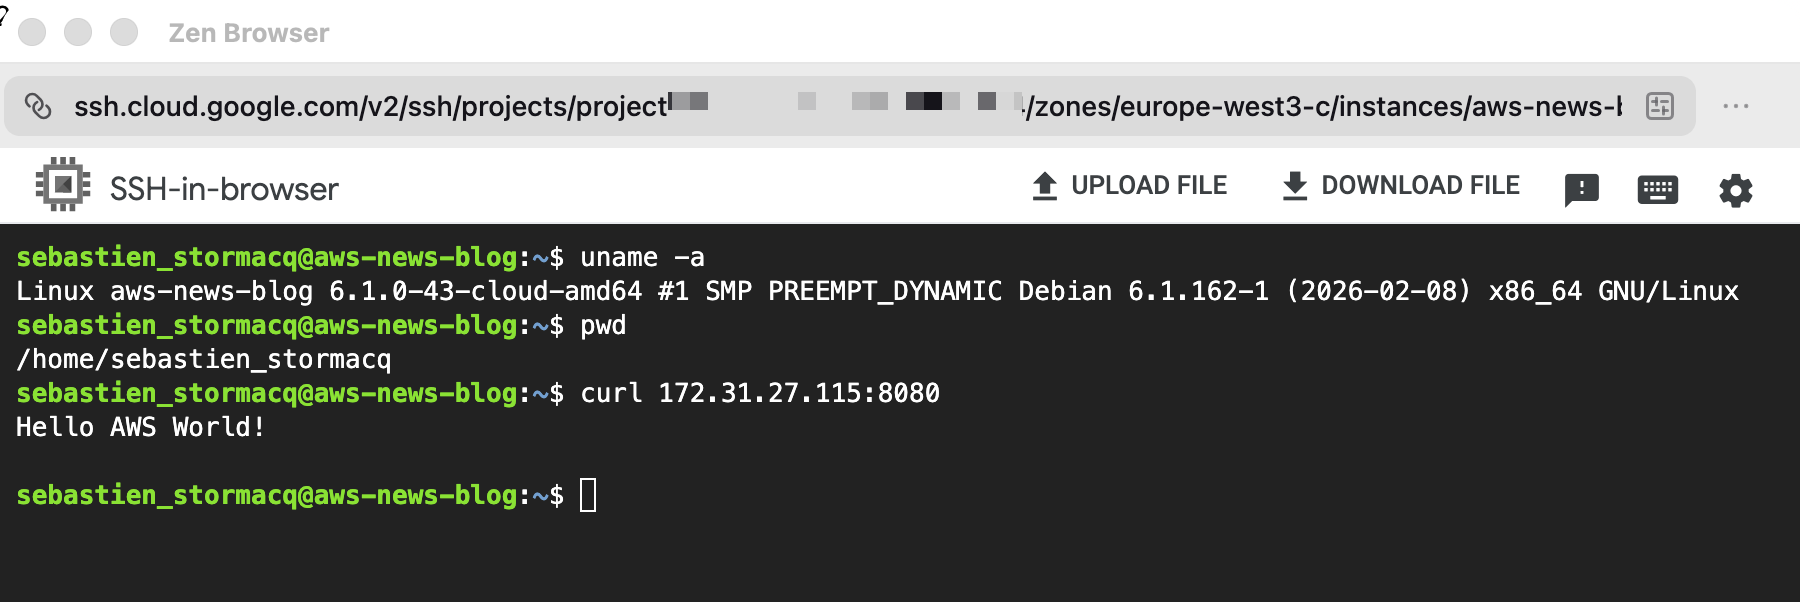
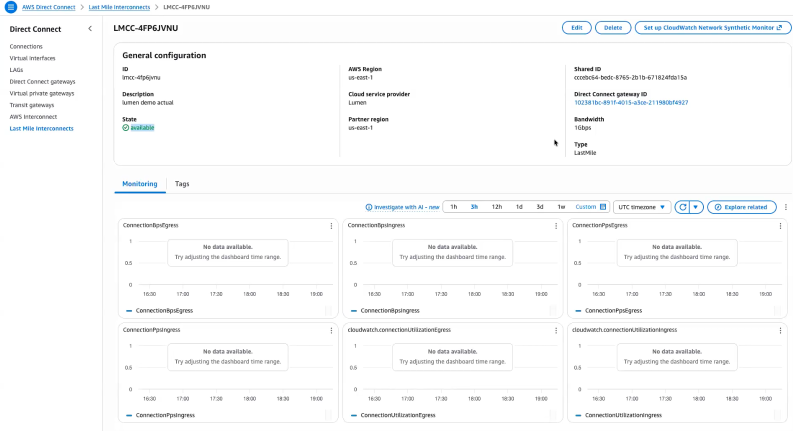
For longer-term resilience, it identifies potential enhancements by examining gaps in observability, infrastructure configurations, and deployment pipeline. My straightforward demo that triggered intentional errors was not enough to generate relevant recommendations though.

AWS DevOps Agent - web app - recommendations

For example, it might detect that a critical service lacks multi-AZ deployment and comprehensive monitoring. The agent then creates detailed recommendations with implementation guidance, considering factors like operational impact and implementation complexity. In an upcoming quick follow-up release, the agent will expand its analysis to include code bugs and testing coverage improvements.

Availability
You can try AWS DevOps Agent today in the US East (N. Virginia) Region. Although the agent itself runs in US East (N. Virginia) (us-east-1), it can monitor applications deployed in any Region, across multiple AWS accounts.

During the preview period, you can use AWS DevOps Agent at no charge, but there will be a limit on the number of agent task hours per month.

As someone who has spent countless nights debugging production issues, I’m particularly excited about how AWS DevOps Agent combines deep operational insights with practical, actionable recommendations. The service helps teams move from reactive firefighting to proactive system improvement.

To learn more and sign up for the preview, visit AWS DevOps Agent. I look forward to hearing how AWS DevOps Agent helps improve your operational efficiency.

— seb

AWS Partner Central now available in AWS Management Console

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/aws-partner-central-now-available-in-aws-management-console/

Today, we’re announcing that AWS Partner Central is now available directly in the AWS Management Console, creating a unified experience that transforms how you engage with AWS as both customers and AWS Partners.

As someone who has worked with countless AWS customers over the years, I’ve observed how organizations evolve in their AWS journey. Many of our most successful Partners began as AWS customers—first using our services to build their own infrastructure and solutions, then expanding to create offerings for others. Seeing this natural progression from customer to Partner, we recognized an opportunity to streamline these traditionally separate experiences into one unified journey.

As AWS evolved, so did the needs of our Partner community. Organizations today operate in multiple capacities: using AWS services for their own infrastructure while simultaneously building and delivering solutions for their customers. Modern businesses need streamlined workflows that support their growth from AWS customer to Partner to AWS Marketplace Seller, with enterprise-grade security features that match how they actually work with AWS today.

A new unified console experience
The integration of AWS Partner Central into the Console represents a fundamental shift in partnership accessibility. For existing AWS customers, such as you, becoming an AWS Partner is now as clear as accessing any other AWS service. The familiar console interface provides direct access to partnership opportunities, program benefits, and AWS Marketplace capabilities without needing separate logins or navigation between different systems.

Getting started as an AWS Partner now takes only a few clicks within your existing console environment. You can discover partnership opportunities, understand program requirements, and begin your Partner journey without leaving the AWS interface you already know and trust.

The console integration creates an intuitive pathway for existing customers to transition into AWS Marketplace Sellers. You can now access AWS Marketplace Seller capabilities alongside your existing AWS services, managing both your infrastructure and AWS Marketplace business from a single interface. Private offer requests and negotiations can be managed directly within AWS Partner Central, and you can manage your AWS Marketplace listings alongside your other AWS activities through streamlined workflows.

Becoming an AWS Partner
The unified console experience provides access to comprehensive partnership benefits designed to accelerate your business growth.

Join the AWS Partner Network (APN) and complete your Partner and AWS Marketplace Seller requirements seamlessly within the same interface. Enroll in Partner Paths that align with your customer solutions to build, market, list, and sell in AWS Marketplace while growing alongside AWS. When you are established, use the Partner programs to differentiate your solution, list in AWS Marketplace to improve your go-to-market discoverability, and build AWS expertise through certifications to drive profitability by capturing new revenue streams. Scale your business by selling or reselling software and professional services in AWS Marketplace, helping you accelerate deals, boost revenue, and expand your customer reach to new geographies, industries, and segments.

Throughout your journey, you can continue using Amazon Q in the console, which provides personalized guidance through AWS Partner Assistant.

Let’s see the new Partner Central console
The new AWS Partner Central is accessible like any other AWS service from the console. Among many new capabilities, it provides four key sections that support Partner operations and business growth within the AWS Partner Network:

1. It helps you sell your solutions

AWS Partner Central - Solutions

You can create and publish solutions that address specific customer needs through AWS Marketplace. Solutions are made up of products such as software as a service (SaaS), Amazon Machine Images (AMI), containers, professional services, AI agents and tools, and more. The solutions management capability guides you through building offerings that include both products you own and those you are authorized to resell. You can craft compelling value propositions and descriptions that clearly communicate your solution benefits to potential buyers browsing AWS Marketplace.

I choose Create solution to start listing a new solution in the AWS Marketplace, as shown in the following figure.

AWS Partner Central - Create solution

2. It helps you update and manage your Partner profile

AWS Partner Central - Manage profile

Your Partner profile showcases your organization’s expertise and capabilities to the AWS community. You control how your business appears to potential customers and Partners by highlighting the industry segments you serve and describing your primary products or services. Profile visibility settings provide you with the option to choose whether your information is public or private.

3. It helps you track opportunities

AWS Partner Central - Track Opportunities

You can manage your pipeline of AWS customers, supporting joint collaborations with AWS on customer engagements. You monitor these prospects using clear status indicators: approved, rejected, draft, and pending approval. The opportunity dashboard shows stages, estimated AWS Monthly Recurring Revenue, and other key metrics that help you understand your pipeline. You can create more opportunities directly within the console and export data for your own reporting and analysis.

4. It provides you with the ability to discover and connect with other Partners

After becoming an AWS Partner, you get access to the AWS Partners network, where you can search for other Partners. You can connect with them to collaborate on sales opportunities and expand your customer outreach.

AWS Partner Central - Discover and Search for partners

You search through available Partners using filters for industry, location, Partner program type, and specialization. The centralized dashboard shows your active connections, pending requests, and connection history, so that you can manage business relationships and identify collaboration opportunities that can expand your reach. Like all other AWS services, these Partner connection capabilities are now available as APIs, which provide automation and integration into your existing workflows.

AWS Partner Central - Manage contact requests

These capabilities work together within the new AWS Partner Central console, accessible directly from the console, helping you transition from AWS customer to successful Partner with enterprise-grade security and streamlined workflows.

The technical foundation: Migrating the identity system
This unified console experience is made possible by our migration to a modern identity system built on AWS Identity and Access Management (IAM). We’ve transitioned from legacy identity infrastructure to IAM Identity Center, providing enterprise-grade security capabilities including single sign-on capabilities and multi-factor authentication. With security as job zero, this migration provides new and existing Partners with the possibility to connect their own identity providers to AWS Partner Central. It provides seamless integration with existing enterprise authentication systems while removing the complexity of managing separate credentials across different services.

One more thing
APIs are the core of what we do at AWS, and AWS Partner Central is no different. You can automate and streamline your co-sell workflows by connecting your business tools to AWS Partner Central. The APIs offered by AWS Partner Central help you accelerate APN benefits—from Account Management (Account API) and Solution Management (Solution API) to co-selling with Opportunity and Leads APIs, and Benefits APIs for faster benefit activation.

You can use these APIs to engage with AWS and grow your Partner business from your own CRM tools.

Get started today
This integration between the console and AWS Partner Central reflects our commitment to reducing complexity and improving the Partner experience. We’re bringing AWS Partner Central into the console to create a more intuitive path for organizations to grow with AWS from initial customer adoption through to full partnership engagement and AWS Marketplace success.

Your journey from AWS customer to successful AWS Partner and AWS Marketplace Seller starts with a few clicks in your console. I encourage you to explore the new unified experience today and discover how AWS Partner Central in the console can accelerate your organization’s growth and success within the AWS community.

Ready to get started? Visit AWS Partner Central in your console to learn more about the AWS Partner Network and discover the partnership path that’s right for your organization.

— seb

Introducing VPC encryption controls: Enforce encryption in transit within and across VPCs in a Region

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/introducing-vpc-encryption-controls-enforce-encryption-in-transit-within-and-across-vpcs-in-a-region/

Today, we’re announcing virtual private cloud (VPC) encryption controls, a new capability of Amazon Virtual Private Cloud (Amazon VPC) that helps you audit and enforce encryption in transit for all traffic within and across VPCs in a Region.

Organizations across financial services, healthcare, government, and retail face significant operational complexity in maintaining encryption compliance across their cloud infrastructure. Traditional approaches require piecing together multiple solutions and managing complex public key infrastructure (PKI), while manually tracking encryption across different network paths using spreadsheets—a process prone to human error that becomes increasingly challenging as infrastructure scales.

Although AWS Nitro based instances automatically encrypt traffic at the hardware layer without affecting performance, organizations need simple mechanisms to extend these capabilities across their entire VPC infrastructure. This is particularly important for demonstrating compliance with regulatory frameworks such as Health Insurance Portability and Accountability (HIPAA), Payment Card Industry Data Security Standard (PCI DSS), and Federal Risk and Authorization Management Program (FedRAMP), which require proof of end-to-end encryption across environments. Organizations need centralized visibility and control over their encryption status, without having to manage performance trade-offs or complex key management systems.

VPC encryption controls address these challenges by providing two operational modes: monitor and enforce. In monitor mode, you can audit the encryption status of your traffic flows and identify resources that allow plaintext traffic. The feature adds a new encryption-status field to VPC flow logs, giving you visibility into whether traffic is encrypted using Nitro hardware encryption, application-layer encryption (TLS), or both.

After you’ve identified resources that need modification, you can take steps to implement encryption. AWS services, such as Network Load Balancer, Application Load Balancer, and AWS Fargate tasks, will automatically and transparently migrate your underlying infrastructure to Nitro hardware without any action required from you and with no service interruption. For other resources, such as the previous generation of Amazon Elastic Compute Cloud (Amazon EC2) instances, you will need to switch to modern Nitro based instance types or configure TLS encryption at application level.

You can switch to enforce mode after all resources have been migrated to encryption-compliant infrastructure. This migration to encryption-compliant hardware and communication protocols is a prerequisite for enabling enforce mode. You can configure specific exclusions for resources such as internet gateways or NAT gateways, that don’t support encryption (because the traffic flows outside of your VPC or the AWS network).

Other resources must be encryption-compliant and can’t be excluded. After activation, enforce mode provides that all future resources are only created on compatible Nitro instances, and unencrypted traffic is dropped when incorrect protocols or ports are detected.

Let me show you how to get started

For this demo, I started three EC2 instances. I use one as a web server with Nginx installed on port 80, serving a clear text HTML page. The other two are continuously making HTTP GET requests to the server. This generates clear text traffic in my VPC. I use the m7g.medium instance type for the web server and one of the two clients. This instance type uses the underlying Nitro System hardware to automatically encrypt in-transit traffic between instances. I use a t4g.medium instance for the other web client. The network traffic of that instance is not encrypted at the hardware level.

To get started, I enable encryption controls in monitor mode. In the AWS Management Console, I select Your VPCs in the left navigation pane, then I switch to the VPC encryption controls tab. I choose Create encryption control and select the VPC I want to create the control for.

Each VPC can have only one VPC encryption control associated with it, creating a one-to-one relationship between the VPC ID and the VPC encryption control Id. When creating VPC encryption controls, you can add tags to help with resource organization and management. You can also activate VPC encryption control when you create a new VPC.

VPC Encryption Control - create EC 1

I enter a Name for this control. I select the VPC I want to control. For existing VPCs, I have to start in Monitor mode, and I can turn on Enforce mode when I’m sure there is no unencrypted traffic. For new VPCs, I can enforce encryption at the time of creation.

Optionally, I can define tags when creating encryption controls for an existing VPC. However, when enabling encryption controls during VPC creation, separate tags can’t be created for VPC encryption controls—because they automatically inherit the same tags as the VPC. When I’m ready, I choose Create encryption control.

VPC Encryption Control - create EC 2Alternatively, I can use the AWS Command Line Interface (AWS CLI):

aws ec2 create-vpc-encryption-control --vpc-id vpc-123456789

Next, I audit the encryption status of my VPC using the console, command line, or flow logs:

aws ec2 create-flow-logs \
  --resource-type VPC \
  --resource-ids vpc-123456789 \
  --traffic-type ALL \
  --log-destination-type s3 \
  --log-destination arn:aws:s3:::vpc-flow-logs-012345678901/vpc-flow-logs/ \
  --log-format '${flow-direction} ${traffic-path} ${srcaddr} ${dstaddr} ${srcport} ${dstport} ${encryption-status}'
{
    "ClientToken": "F7xmLqTHgt9krTcFMBHrwHmAZHByyDXmA1J94PsxWiU=",
    "FlowLogIds": [
        "fl-0667848f2d19786ca"
    ],
    "Unsuccessful": []
}

After a few minutes, I see this traffic in my logs:

flow-direction traffic-path srcaddr dstaddr srcport dstport encryption-status
ingress - 10.0.133.8 10.0.128.55 43236 80 1 # <-- HTTP between web client and server. Encrypted at hardware-level
egress 1 10.0.128.55 10.0.133.8 80 43236 1
ingress - 10.0.133.8 10.0.128.55 36902 80 1
egress 1 10.0.128.55 10.0.133.8 80 36902 1
ingress - 10.0.130.104 10.0.128.55 55016 80 0 # <-- HTTP between web client and server. Not encrypted at hardware-level
egress 1 10.0.128.55 10.0.130.104 80 55016 0
ingress - 10.0.130.104 10.0.128.55 60276 80 0
egress 1 10.0.128.55 10.0.130.104 80 60276 0
  • 10.0.128.55 is the web server with hardware-encrypted traffic, serving clear text traffic at application level.
  • 10.0.133.8 is the web client with hardware-encrypted traffic.
  • 10.0.130.104 is the web client with no encryption at the hardware level.

The encryption-status field tells me the status of the encryption for the traffic between the source and destination address:

  • 0 means the traffic is in clear text
  • 1 means the traffic is encrypted at the network layer (Level 3) by the Nitro system
  • 2 means the traffic is encrypted at the application layer (Level7, TCP Port 443 and TLS/SSL)
  • 3 means the traffic is encrypted both at the application layer (TLS) and the network layer (Nitro)
  • “-” means VPC encryption controls are not enabled, or AWS Flow Logs don’t have the status information.

The traffic originating from the web client on the instance that isn’t Nitro based (10.0.130.104), is flagged as 0. The traffic initiated from the web client on the Nitro- ased instance (10.0.133.8) is flagged as 1.

I also use the console to identify resources that need modification. It reports two nonencrypted resources: the internet gateway and the elastic network interface (ENI) of the instance that isn’t based on Nitro.

VPC Encryption Control - list of exclusionsI can also check for nonencrypted resources using the CLI:

aws ec2 get-vpc-resources-blocking-encryption-enforcement --vpc-id vpc-123456789

After updating my resources to support encryption, I can use the console or the CLI to switch to enforce mode.

In the console, I select the VPC encryption control. Then, I select Actions and Switch mode.

VPC Encryption Control - switch modeOr the equivalent CLI:

aws ec2 modify-vpc-encryption-control --vpc-id vpc-123456789 --mode enforce

How to modify the resources that are identified as nonencrypted?

All your VPC resources must support traffic encryption, either at the hardware layer or at the application layer. For most resources, you don’t need to take any action.

AWS services accessed through AWS PrivateLink and gateway endpoints automatically enforce encryption at the application layer. These services only accept TLS-encrypted traffic. AWS will automatically drop any traffic that isn’t encrypted at the application layer.

When you enable monitor mode, we automatically and gradually migrate your Network Load Balancers, Application Load Balancers, AWS Fargate clusters, and Amazon Elastic Kubernetes Service (Amazon EKS) clusters to hardware that inherently supports encryption. This migration happens transparently without any action required from you.

Some VPC resources require you to select the underlying instances that support modern Nitro hardware-layer encryption. These include EC2 Instances, Auto Scaling groups, Amazon Relational Database Service (Amazon RDS) databases (including Amazon DocumentDB), Amazon ElastiCache node-based clusters, Amazon Redshift provisioned clusters, EKS clusters, ECS with EC2 capacity, MSK Provisioned, Amazon OpenSearch Service, and Amazon EMR. To migrate your Redshift clusters, you must create a new cluster or namespace from a snapshot.

If you use newer-generation instances, you likely already have encryption-compliant infrastructure because all recent instance types support encryption. For older-generation instances that don’t support encryption-in transit, you’ll need to upgrade to supported instance types.

Something to know when using AWS Transit Gateway

When creating a Transit Gateway through AWS CloudFormation with VPC encryption enabled, you need two additional AWS Identity and Access Management (IAM) permissions: ec2:ModifyTransitGateway and ec2:ModifyTransitGatewayOptions. These permissions are required because CloudFormation uses a two-step process to create a Transit Gateway. It first creates the Transit Gateway with basic configuration, then calls ModifyTransitGateway to enable encryption support. Without these permissions, your CloudFormation stack will fail during creation when attempting to apply the encryption configuration, even if you’re only performing what appears to be a create operation.

Pricing and availability

You can start using VPC encryption controls today in these AWS Regions: US East (Ohio, N. Virginia), US West (N. California, Oregon), Africa (Cape Town), Asia Pacific (Hong Kong, Hyderabad, Jakarta, Melbourne, Mumbai, Osaka, Singapore, Sydney, Tokyo), Canada (Central), Canada West (Calgary), Europe (Frankfurt, Ireland, London, Milan, Paris, Stockholm, Zurich), Middle East (Bahrain, UAE), and South America (São Paulo).

VPC encryption controls is free of cost until March 1, 2026. The VPC pricing page will be updated with details as we get closer to that date.

To learn more, visit the VPC encryption controls documentation or try it out in your AWS account. I look forward to hearing how you use this feature to strengthen your security posture and help you meet compliance standards.

— seb

New Amazon Bedrock service tiers help you match AI workload performance with cost

Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/new-amazon-bedrock-service-tiers-help-you-match-ai-workload-performance-with-cost/

Today, Amazon Bedrock introduces new service tiers that give you more control over your AI workload costs while maintaining the performance levels your applications need.

I’m working with customers building AI applications. I’ve seen firsthand how different workloads require different performance and cost trade-offs. Many organizations running AI workloads face challenges balancing performance requirements with cost optimization. Some applications need rapid response times for real-time interactions, whereas others can process data more gradually. With these challenges in mind, today we’re announcing additional options pricing that give you more flexibility in matching your workload requirements with cost optimization.

Amazon Bedrock now offers three service tiers for workloads: Priority, Standard, and Flex. Each tier is designed to match specific workload requirements. Applications have varying response time requirements based on the use case. Some applications—such as financial trading systems—demand the fastest response times, others need rapid response times to support business processes like content generation, and applications such as content summarization can process data more gradually.

The Priority tier processes your requests ahead of other tiers, providing preferential compute allocation for mission-critical applications like customer-facing chat-based assistants and real-time language translation services, though at a premium price point. The Standard tier provides consistent performance at regular rates for everyday AI tasks, ideal for content generation, text analysis, and routine document processing. For workloads that can handle longer latency, the Flex tier offers a more cost-effective option with lower pricing, which is well suited for model evaluations, content summarization, and multistep analysis and agentic workflows.

You can now optimize your spending by matching each workload to the most appropriate tier. For example, if you’re running a customer service chat-based assistant that needs quick responses, you can use the Priority tier to get the fastest processing times. For content summarization tasks that can tolerate longer processing times, you can use the Flex tier to reduce costs while maintaining reliable performance. For most models that support Priority Tier, customers can realize up to 25% better output tokens per second (OTPS) latency compared to standard tier.

Check the Amazon Bedrock documentation for an up-to-date list of models supported for each service tier.

Choosing the right tier for your workload

Here is a mental model to help you choose the right tier for your workload.

Category Recommended service tier Description
Mission-critical Priority Requests are handled ahead of other tiers. Lower latency responses for user-facing apps (for example, customer service chat assistants, real-time language translation, interactive AI assistants)
Business-standard Standard Responsive performance for important workloads (for example, content generation, text analysis, routine document processing)
Business-noncritical Flex Cost-efficient for less urgent workloads (for example, model evaluations, content summarization, multistep agentic workflows)

Start by reviewing with application owners your current usage patterns. Next, identify which workloads need immediate responses and which ones can process data more gradually. You can then begin routing a small portion of your traffic through different tiers to test performance and cost benefits.

The AWS Pricing Calculator helps you estimate costs for different service tiers by entering your expected workload for each tier. You can estimate your budget based on your specific usage patterns.

To monitor your usage and costs, you can use the AWS Service Quotas console or turn on model invocation logging in Amazon Bedrock and observe the metrics with Amazon CloudWatch. These tools provide visibility into your token usage and help you track performance across different tiers.

Amazon Bedrock invocations observability

You can start using the new service tiers today. You choose the tier on a per-API call basis. Here is an example using the ChatCompletions OpenAI API, but you can pass the same service_tier parameter in the body of InvokeModel, InvokeModelWithResponseStream, Converse, andConverseStream APIs (for supported models):

from openai import OpenAI

client = OpenAI(
    base_url="https://bedrock-runtime.us-west-2.amazonaws.com/openai/v1",
    api_key="$AWS_BEARER_TOKEN_BEDROCK" # Replace with actual API key
)

completion = client.chat.completions.create(
    model= "openai.gpt-oss-20b-1:0",
    messages=[
        {
            "role": "developer",
            "content": "You are a helpful assistant."
        },
        {
            "role": "user",
            "content": "Hello!"
        }
    ]
    service_tier= "priority"  # options: "priority | default | flex"
)

print(completion.choices[0].message)

To learn more, check out the Amazon Bedrock User Guide or contact your AWS account team for detailed planning assistance.

I’m looking forward to hearing how you use these new pricing options to optimize your AI workloads. Share your experience with me online on social networks or connect with me at AWS events.

— seb