Cloudflare acquires Outerbase to expand database and agent developer experience capabilities

Post Syndicated from Brandon Strittmatter original https://blog.cloudflare.com/cloudflare-acquires-outerbase-database-dx/

I’m thrilled to share that Cloudflare has acquired Outerbase. This is such an amazing opportunity for us, and I want to explain how we got here, what we’ve built so far, and why we are so excited about becoming part of the Cloudflare team.

Databases are key to building almost any production application: you need to persist state for your users (or agents), be able to query it from a number of different clients, and you want it to be fast. But databases aren’t always easy to use: designing a good schema, writing performant queries, creating indexes, and optimizing your access patterns tends to require a lot of experience. Add that to exposing your data through easy-to-grok APIs that make the ‘right’ way to do things obvious, a great developer experience (from dashboard to CLI), and well… there’s a lot of work involved.

The Outerbase team is already getting to work on some big changes to how databases (and your data) are viewed, edited, and visualized from within Workers, and we’re excited to give you a few sneak peeks into what we’ll be landing as we get to work.

Database DX

When we first started Outerbase, we saw how complicated databases could be. Even experienced developers struggled with writing queries, indexing data, and locking down their data. Meanwhile, non-developers often felt locked out and that they couldn’t access the data they needed. We believed there had to be a better way. From day one, our goal was to make data accessible to everyone, no matter their skill level. While it started out by simply building a better database interface, it quickly evolved into something much more special.

Outerbase became a platform that helps you manage data in a way that feels natural. You can browse tables, edit rows, and run queries without having to deal with memorizing SQL structure. Even if you do know SQL, you can use Outerbase to dive in deeper and share your knowledge with your team. We also added visualization features so entire teams, both technical and not, could see what’s happening with their data at a glance. Then, with the growth of AI, we realized we could use it to handle many of the more complicated tasks.

One of our more exciting offerings is Starbase, a SQLite-compatible database built on top of Cloudflare’s Durable Objects. Our goal was never to simply wrap a legacy system in a shiny interface; we wanted to make it so easy to get started from day one with nothing, and Cloudflare’s Durable Objects gave us a way to easily manage and spin up databases for anyone who needed one. On top of them, we provided automatic REST APIs, row-level security, WebSocket support for streaming queries, and much more.

1 + 1 = 3

Our collaboration with Cloudflare first started last year, when we introduced a way for developers to import and manage their D1 databases inside Outerbase. We were impressed with how powerful Cloudflare’s tools are for deploying and scaling applications. As we worked together, we quickly saw how well our missions aligned. Cloudflare was building the infrastructure we wished we’d had when we first started, and we were building the data experience that many Cloudflare developers were asking for. This eventually led to the seemingly obvious decision of Outerbase joining Cloudflare — it just made so much sense.

Going forward, we’ll integrate Outerbase’s core features into Cloudflare’s platform. If you’re a developer using D1 or Durable Objects, you’ll start seeing features from Outerbase show up in the Cloudflare dashboard. Expect to see our data explorer for browsing and editing tables, new REST APIs, query editor with type-ahead functionality, real-time data capture, and more of the other tooling we’ve been refining over the last couple of years show up inside the Cloudflare dashboard.

As part of this transition, the hosted Outerbase cloud will shut down on October 15, 2025, which is about six months from now. We know some of you rely on Outerbase as it stands today, so we’re leaving the open-source repositories as they are.

You will still be able to self-host Outerbase if you prefer, and we’ll provide guidance on how to do that within your own Cloudflare account. Our main goal will be to ensure that the best parts of Outerbase become part of the Cloudflare developer experience, so you no longer have to make a choice (it’ll be obvious!).

Sneak peek

We’ve already done a lot of thinking about how we’re going to bring the best parts of Outerbase into D1, Durable Objects, Workflows, and Agents, and we’re going to a share a little about what will be landing over the course of Q2 2025 as the Outerbase team gets to work.

Specifically, we’ll be heads-down focusing on:

  • Adapting the powerful table viewer and query runner experiences to D1 and Durable Objects (amongst many other things!)

  • Making it easier to get started with Durable Objects: improving the experience in Wrangler (our CLI tooling), the Cloudflare dashboard, and how you plug into them from your client applications

  • Improvements to how you visualize the state of a Workflow and the (thousands to millions!) of Workflow instances you might have at any point in time

  • Pre- and post-query hooks for D1 that allow you to automatically register handlers that can act on your data

  • Bringing the Starbase API to D1, expanding D1’s existing REST API, and adding WebSockets support — making it easier to use D1, even for applications hosted outside of Workers.

We have already started laying the groundwork for these changes. In the coming weeks, we’ll release a unified data explorer for D1 and Durable Objects that borrows heavily from the Outerbase interface you know. 
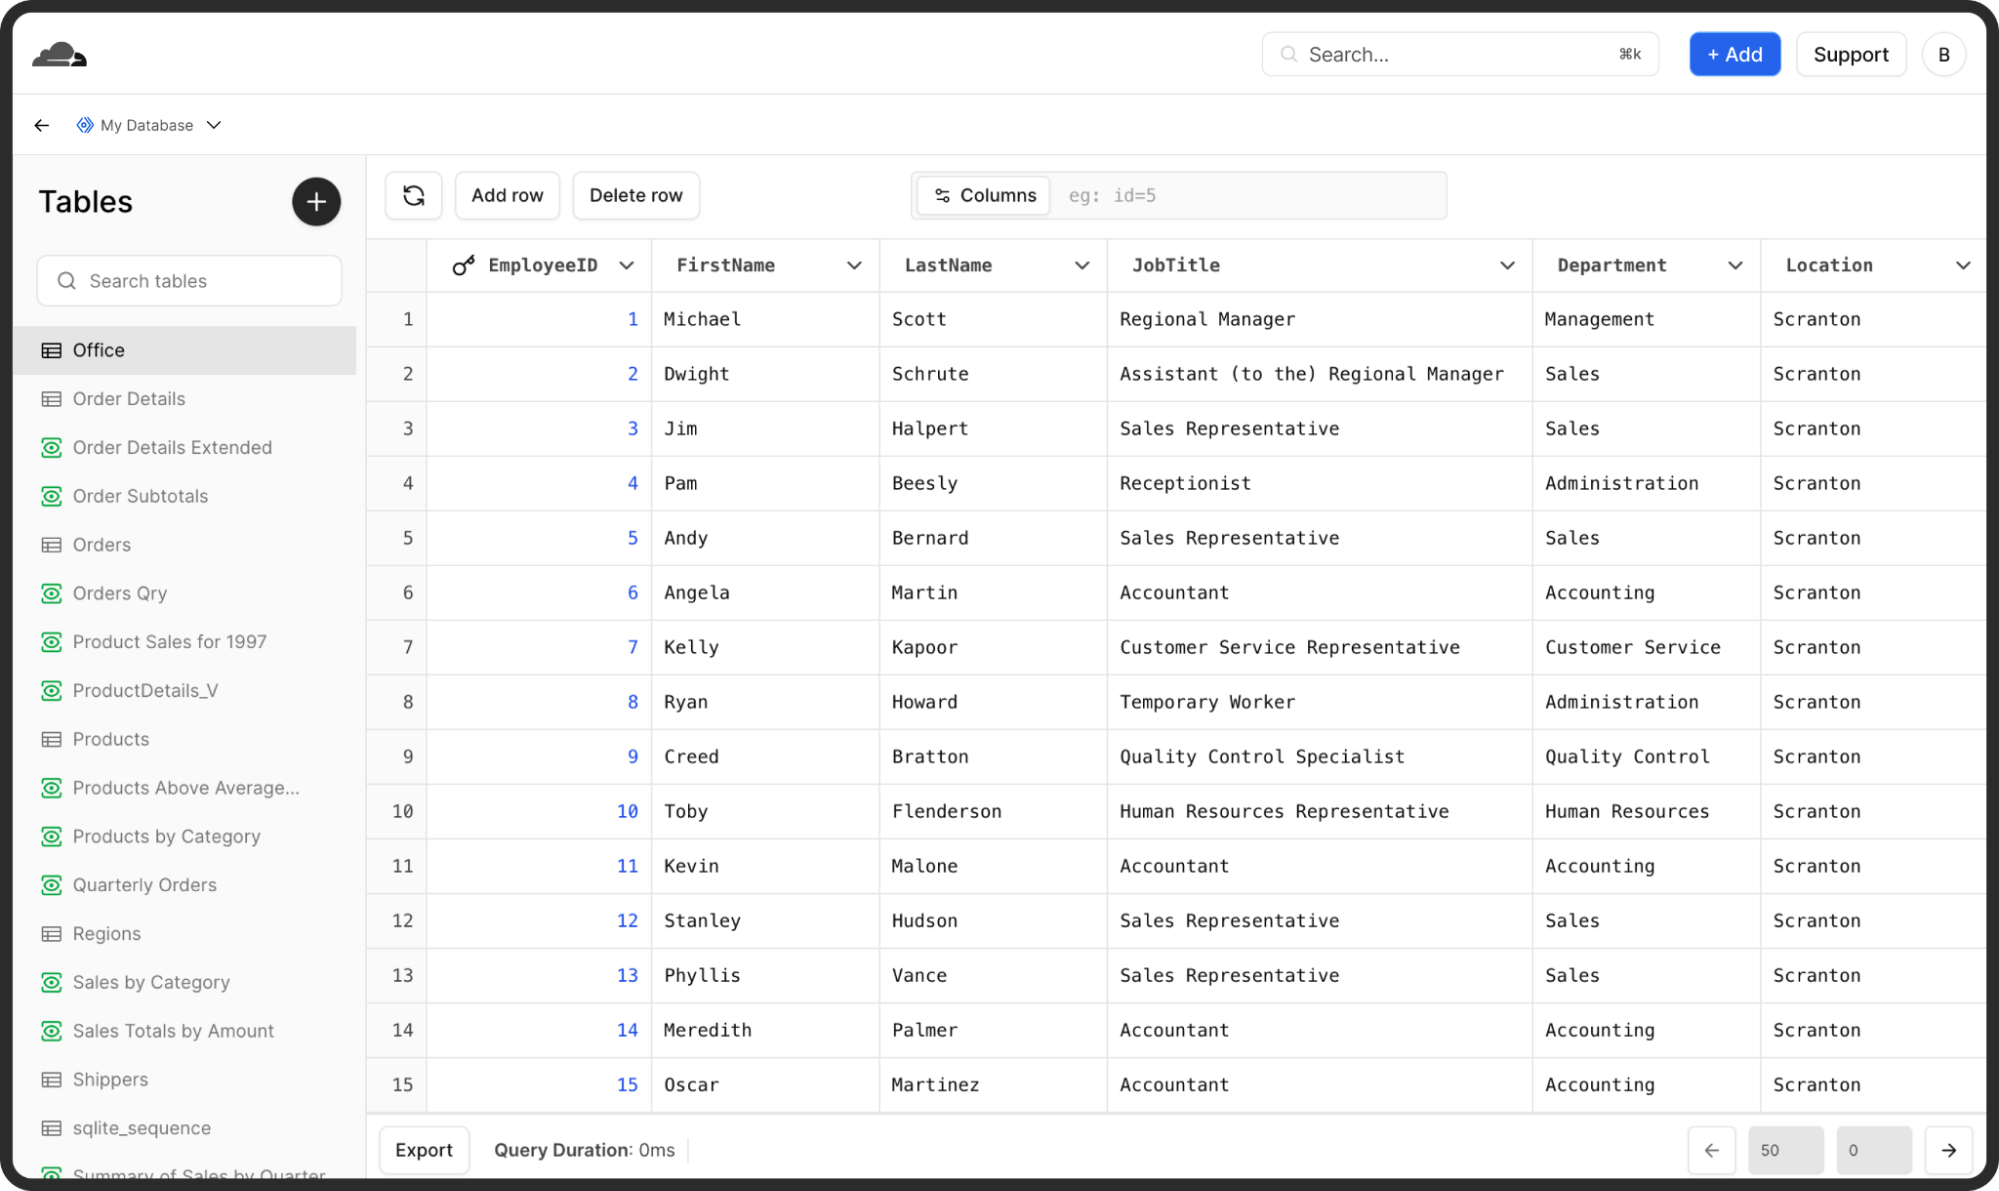

Bringing Outerbase’s Data Explorer into the Cloudflare Dashboard

We’ll also tie some of Starbase’s features directly into Cloudflare’s platform, so you can tap into its unique offerings like pre- and post-query hooks or row-level security right from your existing D1 databases and Durable Objects:

const beforeQuery = ({ sql, params }) => {
    // Prevent unauthorized queries
    if (!isAllowedQuery(sql)) throw new Error('Query not allowed');
};

const afterQuery = ({ sql, result }) => {
    // Basic PII masking example
    for (const row of result) {
        if ('email' in row) row.email = '[redacted]';
    }
};

// Execute the query with pre- and post- query hooks
const { results } = await env.DB.prepare("SELECT * FROM users;", beforeQuery, afterQuery);

Define hooks on your D1 queries that can be re-used, shared and automatically executed before or after your queries run.

This should give you more clarity and control over your data, as well as new ways to secure and optimize it.
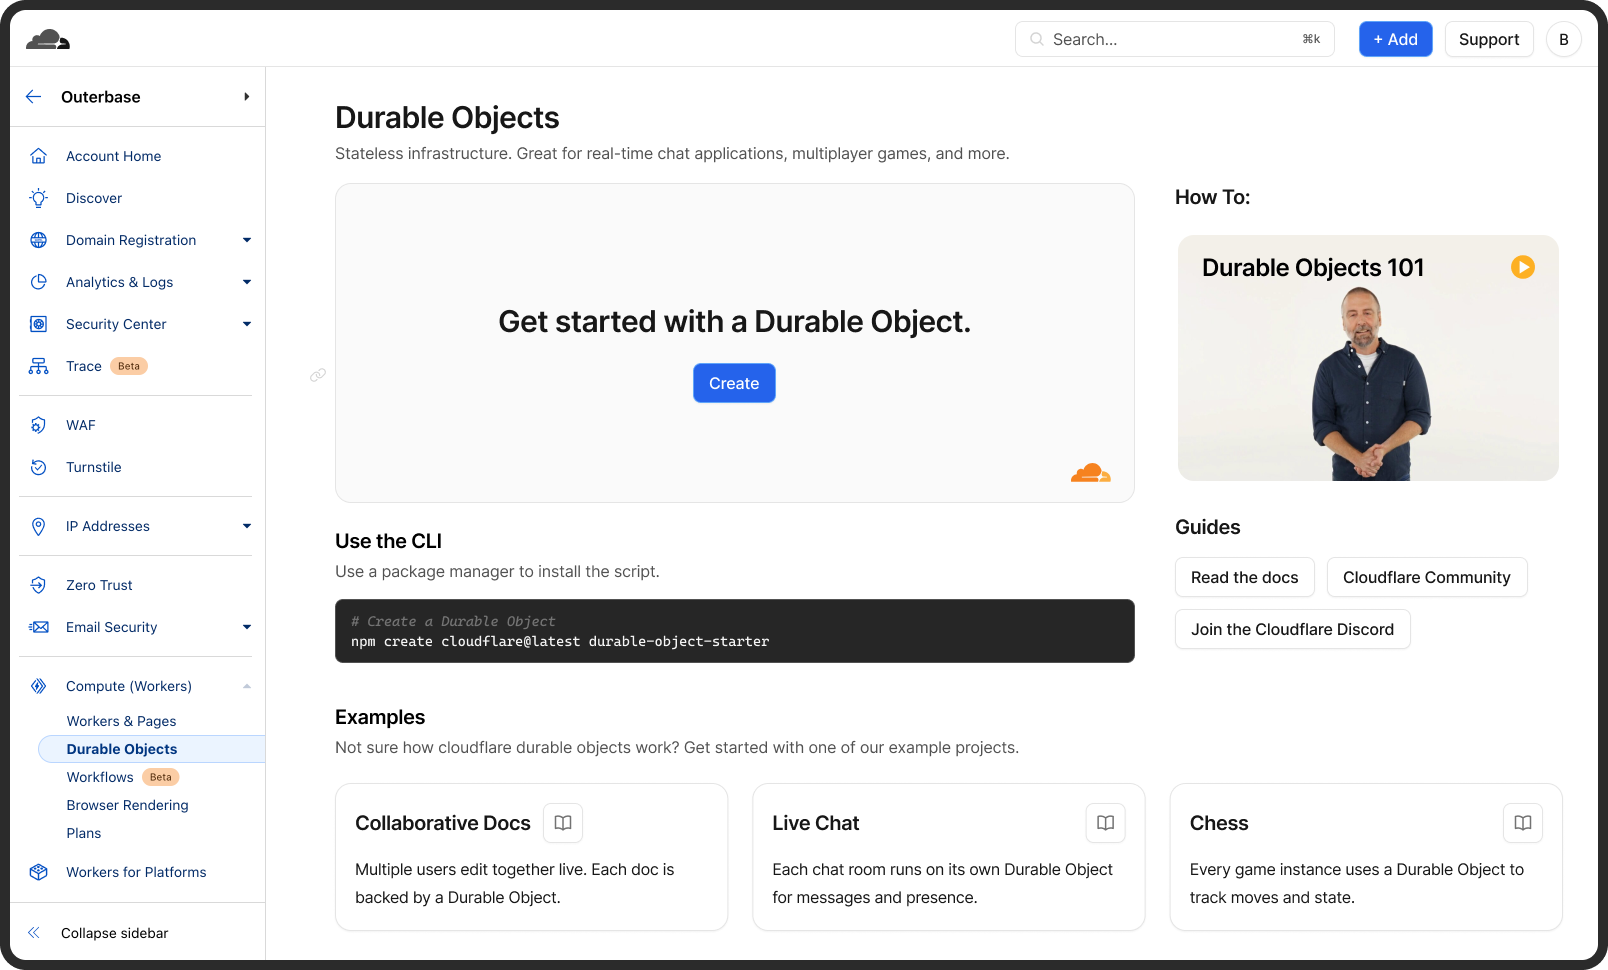

Rethinking the Durable Objects getting started experience

We have even begun optimizing the Cloudflare dashboard experience around Durable Objects and D1 to improve the empty state, provide more Getting Started resources, and overall, make managing and tracking your database resources even easier.

For those of you who’ve supported us, given us feedback, and stuck with us as we grew: thank you. You have helped shape Outerbase into what it is today. This acquisition means we can pour even more resources and attention into building the data experience we’ve always wanted to deliver. Our hope is that, by working as part of Cloudflare, we can help reach even more developers by building intuitive experiences, accelerating the speed of innovation, and creating tools that naturally fit into your workflows.

This is a big step for Outerbase, and we couldn’t be more excited. Thank you for being part of our journey so far. We can’t wait to show you what we’ve got in store as we continue to make data more accessible, intuitive, and powerful — together with Cloudflare.

What’s next?

We’re planning to get to work on some of the big changes to how you interact with your data on Cloudflare, starting with D1 and Durable Objects.

We’ll also be ensuring we bring a great developer experience to the broader database & storage platform on Cloudflare, including how you access data in Workers KV, R2, Workflows and even your AI Agents (just to name a few).

To keep up, follow the new Cloudflare Changelog and join our Developer Discord to chat with the team and see early previews before they land.
Cloudflare Workflows is now GA: production-ready durable execution

Post Syndicated from Sid Chatterjee original https://blog.cloudflare.com/workflows-ga-production-ready-durable-execution/

Betas are useful for feedback and iteration, but at the end of the day, not everyone is willing to be a guinea pig or can tolerate the occasional sharp edge that comes along with beta software. Sometimes you need that big, shiny “Generally Available” label (or blog post), and now it’s Workflows’ turn.

Workflows, our serverless durable execution engine that allows you to build long-running, multi-step applications (some call them “step functions”) on Workers, is now GA.

In short, that means it’s production ready —  but it also doesn’t mean Workflows is going to ossify. We’re continuing to scale Workflows (including more concurrent instances), bring new capabilities (like the new waitForEvent API), and make it easier to build AI agents with our Agents SDK and Workflows.

If you prefer code to prose, you can quickly install the Workflows starter project and start exploring the code and the API with a single command:

npm create cloudflare@latest workflows-starter -- 
--template="cloudflare/workflows-starter"

How does Workflows work? What can I build with it? How do I think about building AI agents with Workflows and the Agents SDK? Well, read on.

Building with Workflows

Workflows is a durable execution engine built on Cloudflare Workers that allows you to build resilient, multi-step applications.

At its core, Workflows implements a step-based architecture where each step in your application is independently retriable, with state automatically persisted between steps. This means that even if a step fails due to a transient error or network issue, Workflows can retry just that step without needing to restart your entire application from the beginning.

When you define a Workflow, you break your application into logical steps.

  • Each step can either execute code (step.do), put your Workflow to sleep (step.sleep or step.sleepUntil), or wait on an event (step.waitForEvent).

  • As your Workflow executes, it automatically persists the state returned from each step, ensuring that your application can continue exactly where it left off, even after failures or hibernation periods. 

  • This durable execution model is particularly powerful for applications that coordinate between multiple systems, process data in sequence, or need to handle long-running tasks that might span minutes, hours, or even days.

Workflows are particularly useful at handling complex business processes that traditional stateless functions struggle with.

For example, an e-commerce order processing workflow might check inventory, charge a payment method, send an email confirmation, and update a database — all as separate steps. If the payment processing step fails due to a temporary outage, Workflows will automatically retry just that step when the payment service is available again, without duplicating the inventory check or restarting the entire process. 

You can see how this works below: each call to a service can be modelled as a step, independently retried, and if needed, recovered from that step onwards:

import { WorkflowEntrypoint, WorkflowStep, WorkflowEvent } from 'cloudflare:workers';

// The params we expect when triggering this Workflow
type OrderParams = {
	orderId: string;
	customerId: string;
	items: Array<{ productId: string; quantity: number }>;
	paymentMethod: {
		type: string;
		id: string;
	};
};

// Our Workflow definition
export class OrderProcessingWorkflow extends WorkflowEntrypoint<Env, OrderParams> {
	async run(event: WorkflowEvent<OrderParams>, step: WorkflowStep) {
		// Step 1: Check inventory
		const inventoryResult = await step.do('check-inventory', async () => {
			console.log(`Checking inventory for order ${event.payload.orderId}`);

			// Mock: In a real workflow, you'd query your inventory system
			const inventoryCheck = await this.env.INVENTORY_SERVICE.checkAvailability(event.payload.items);

			// Return inventory status as state for the next step
			return {
				inStock: true,
				reservationId: 'inv-123456',
				itemsChecked: event.payload.items.length,
			};
		});

		// Exit workflow if items aren't in stock
		if (!inventoryResult.inStock) {
			return { status: 'failed', reason: 'out-of-stock' };
		}

		// Step 2: Process payment
		// Configure specific retry logic for payment processing
		const paymentResult = await step.do(
			'process-payment',
			{
				retries: {
					limit: 3,
					delay: '30 seconds',
					backoff: 'exponential',
				},
				timeout: '2 minutes',
			},
			async () => {
				console.log(`Processing payment for order ${event.payload.orderId}`);

				// Mock: In a real workflow, you'd call your payment processor
				const paymentResponse = await this.env.PAYMENT_SERVICE.processPayment({
					customerId: event.payload.customerId,
					orderId: event.payload.orderId,
					amount: calculateTotal(event.payload.items),
					paymentMethodId: event.payload.paymentMethod.id,
				});

				// If payment failed, throw an error that will trigger retry logic
				if (paymentResponse.status !== 'success') {
					throw new Error(`Payment failed: ${paymentResponse.message}`);
				}

				// Return payment info as state for the next step
				return {
					transactionId: 'txn-789012',
					amount: 129.99,
					timestamp: new Date().toISOString(),
				};
			},
		);

		// Step 3: Send email confirmation
		await step.do('send-confirmation-email', async () => {
			console.log(`Sending confirmation email for order ${event.payload.orderId}`);
			console.log(`Including payment confirmation ${paymentResult.transactionId}`);
			return await this.env.EMAIL_SERVICE.sendOrderConfirmation({ ... })
		});

		// Step 4: Update database
		const dbResult = await step.do('update-database', async () => {
			console.log(`Updating database for order ${event.payload.orderId}`);
			await this.updateOrderStatus(...)

			return { dbUpdated: true };
		});

		// Return final workflow state
		return {
			orderId: event.payload.orderId,
			processedAt: new Date().toISOString(),
		};
	}
}

This combination of durability, automatic retries, and state persistence makes Workflows ideal for building reliable distributed applications that can handle real-world failures gracefully.

Human-in-the-loop

Workflows are just code, and that makes them extremely powerful: you can define steps dynamically and on-the-fly, conditionally branch, and make API calls to any system you need. But sometimes you also need a Workflow to wait for something to happen in the real world.

For example:

  • Approval from a human to progress.

  • An incoming webhook, like from a Stripe payment or a GitHub event.

  • A state change, such as a file upload to R2 that triggers an Event Notification, and then pushes a reference to the file to the Workflow, so it can process the file (or run it through an AI model).

The new waitForEvent API in Workflows allows you to do just that: 

let event = await step.waitForEvent<IncomingStripeWebhook>("receive invoice paid webhook from Stripe", { type: "stripe-webhook", timeout: "1 hour" }) 

You can then send an event to a specific instance from any external service that can make a HTTP request:

curl -d '{"transaction":"complete","id":"1234-6789"}' \
  -H "Authorization: Bearer ${CF_TOKEN}" \
\ "https://api.cloudflare.com/client/v4/accounts/{account_id}/workflows/{workflow_name}/instances/{instance_id}/events/{event_type}"

… or via the Workers API within a Worker itself:

interface Env {
  MY_WORKFLOW: Workflow;
}

interface Payload {
  transaction: string;
  id: string;
}

export default {
  async fetch(req: Request, env: Env) {
    const instanceId = new URL(req.url).searchParams.get("instanceId")
    const webhookPayload = await req.json<Payload>()

    let instance = await env.MY_WORKFLOW.get(instanceId);
    // Send our event, with `type` matching the event type defined in
    // our step.waitForEvent call
    await instance.sendEvent({type: "stripe-webhook", payload: webhookPayload})
    
    return Response.json({
      status: await instance.status(),
    });
  },
};

You can even wait for multiple events, using the type parameter, and/or race multiple events using Promise.race to continue on depending on which event was received first:

export class MyWorkflow extends WorkflowEntrypoint<Env, Params> {
	async run(event: WorkflowEvent<Params>, step: WorkflowStep) {
		let state = await step.do("get some data", () => { /* step call here /* })
		// Race the events, resolving the Promise based on which event
// we receive first
		let value = Promise.race([
step.waitForEvent("payment success", { type: "payment-success-webhook", timeout: "4 hours" ),
step.waitForEvent("payment failure", { type: "payment-failure-webhook", timeout: "4 hours" ),
])
// Continue on based on the value and event received
	}
}

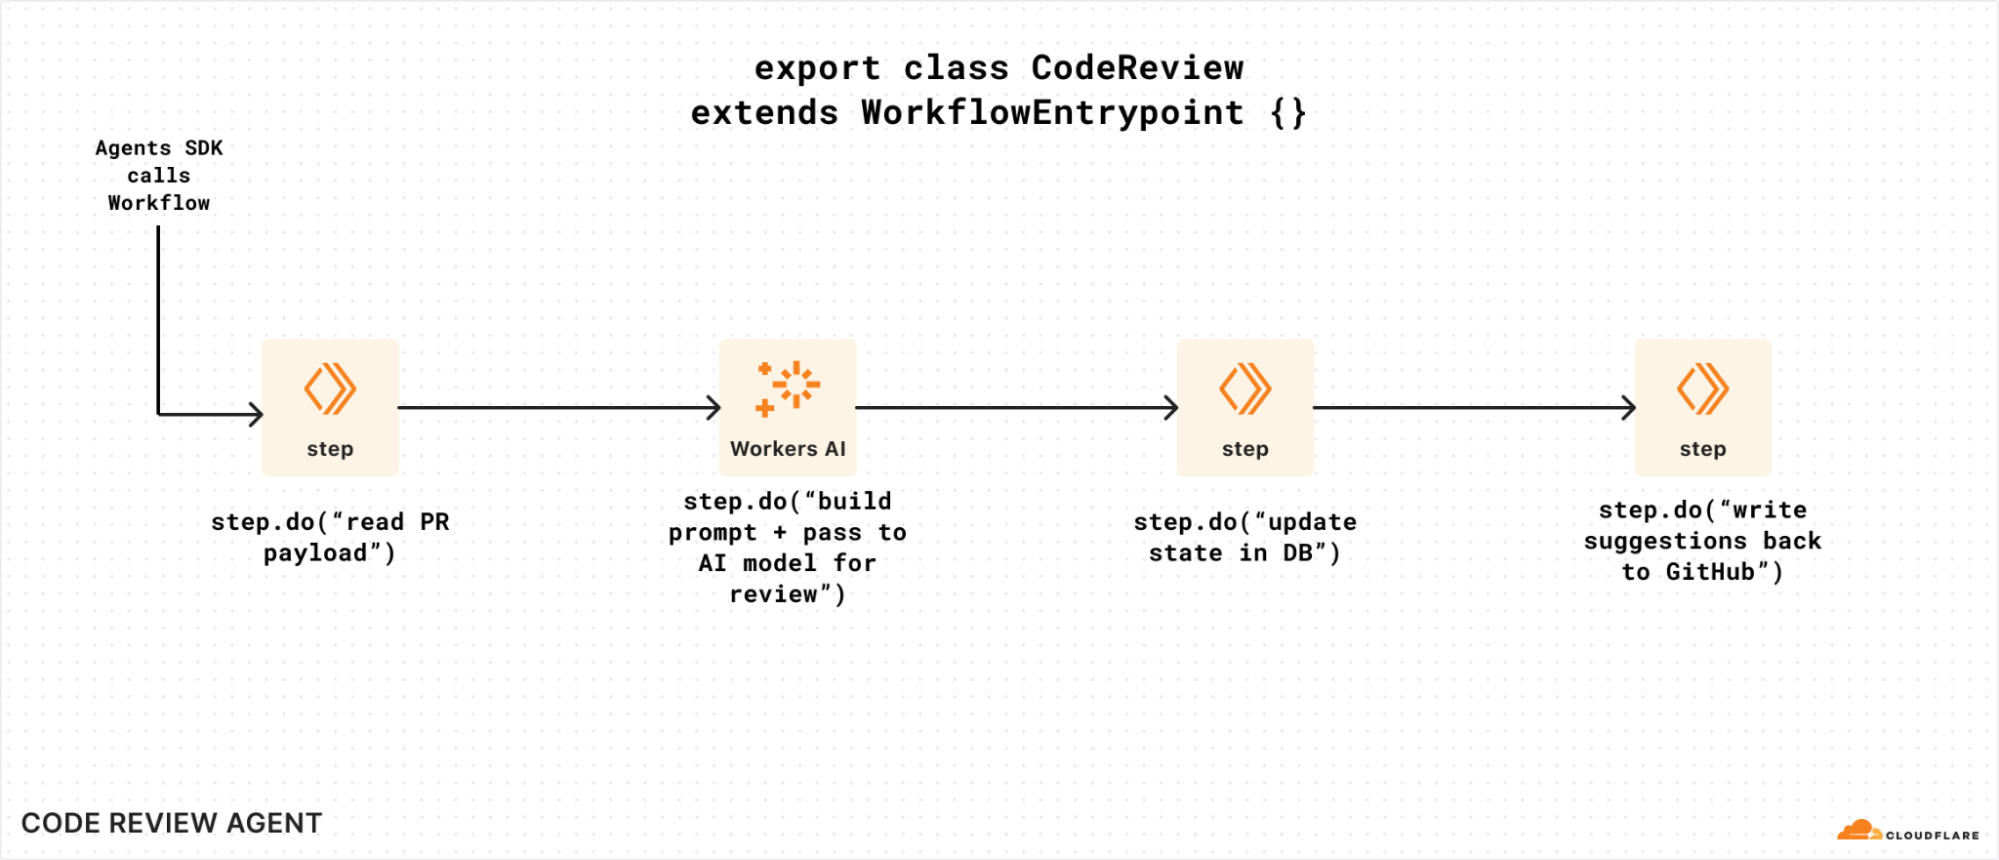
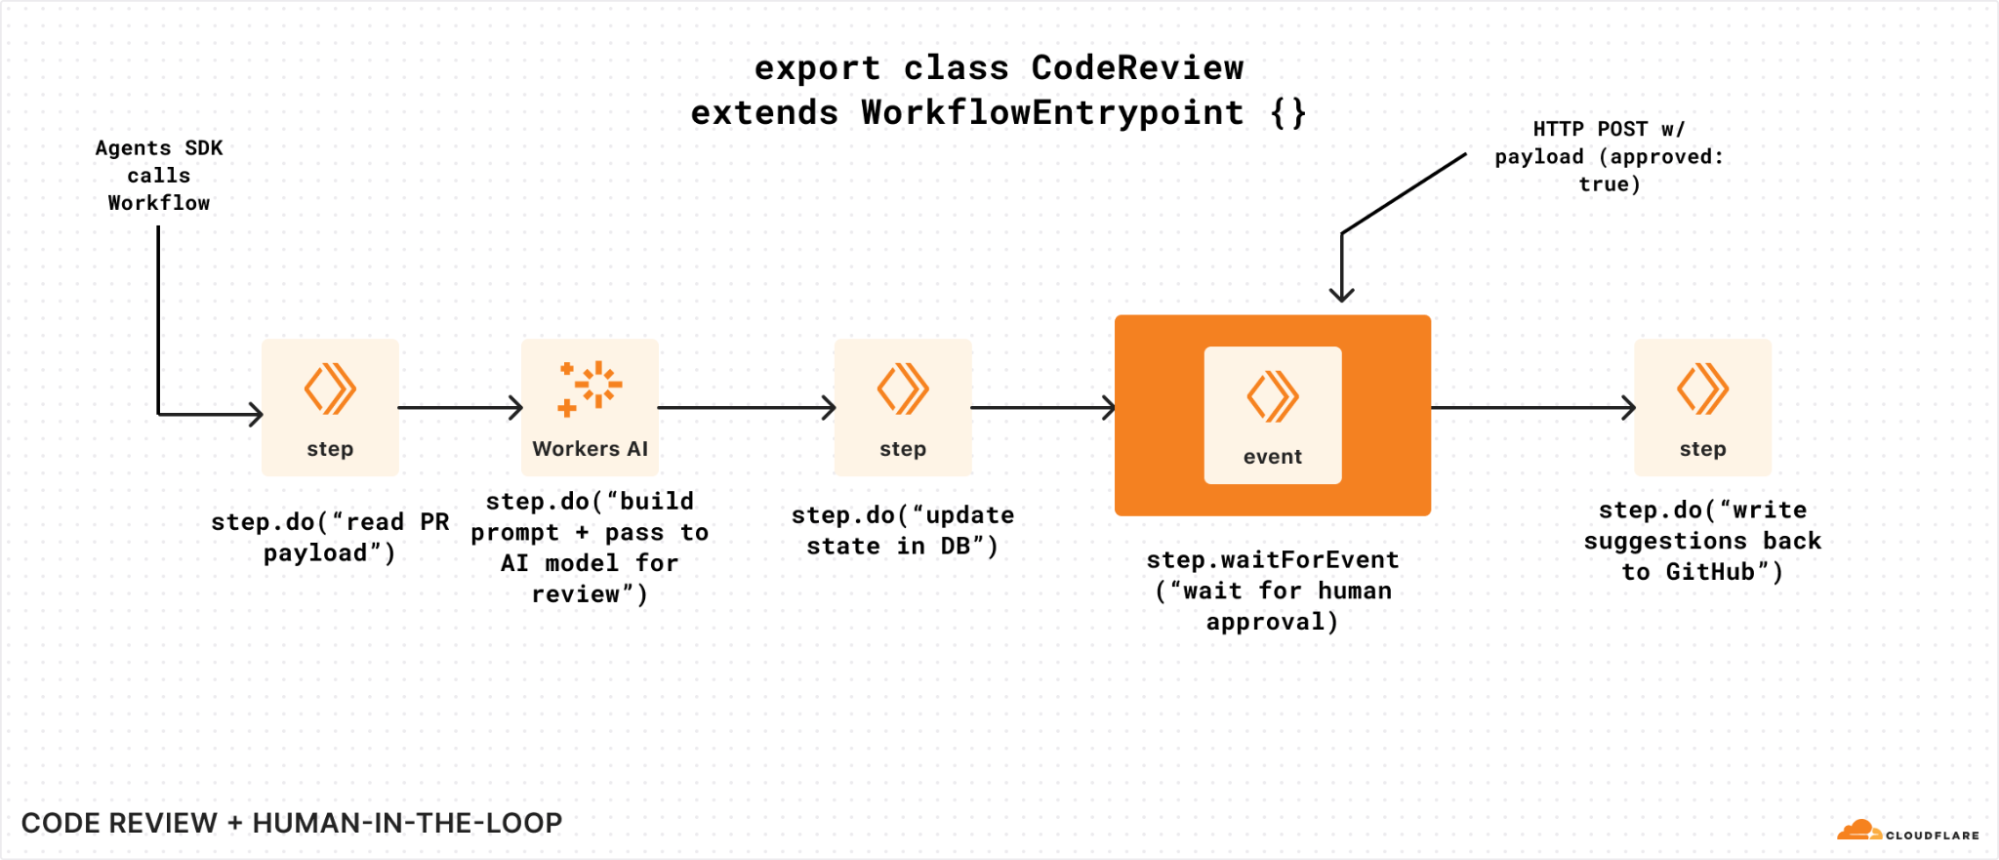
To visualize waitForEvent in a bit more detail, let’s assume we have a Workflow that is triggered by a code review agent that watches a GitHub repository.

Without the ability to wait on events, our Workflow can’t easily get human approval to write suggestions back (or even submit a PR of its own). It could potentially poll for some state that was updated, but that means we have to call step.sleep for arbitrary periods of time, poll a storage service for an updated value, and repeat if it’s not there. That’s a lot of code and room for error:


Without waitForEvent, it’s harder to send data to a Workflow instance that’s running

If we modified that same example to incorporate the new waitForEvent API, we could use it to wait for human approval before making a mutating change: 


Adding waitForEvent to our code review Workflow, so it can seek explicit approval.

You could even imagine an AI agent itself sending and/or acting on behalf of a human here: waitForEvent simply exposes a way for a Workflow to retrieve and pause on something in the world to change before it continues (or not).

Critically, you can call waitForEvent just like any other step in Workflows: you can call it conditionally, and/or multiple times, and/or in a loop. Workflows are just Workers: you have the full power of a programming language and are not restricted by a domain specific language (DSL) or config language.

Pricing

Good news: we haven’t changed much since our original beta announcement! We’re adding storage pricing for state stored by your Workflows, and retaining our CPU-based and request (invocation) based pricing as follows:

Unit

Workers Free

Workers Paid

CPU time (ms)

10 ms per Workflow

30 million CPU milliseconds included per month

+$0.02 per additional million CPU milliseconds

Requests

100,000 Workflow invocations per day (shared with Workers)

10 million included per month

+$0.30 per additional million

Storage (GB)

1 GB

1 GB included per month
+ $0.20/ GB-month

Because the storage pricing is new, we will not actively bill for storage until September 15, 2025. We will notify users above the included 1 GB limit ahead of charging for storage, and by default, Workflows will expire stored state after three (3) days (Free plan) or thirty (30) days (Paid plan).

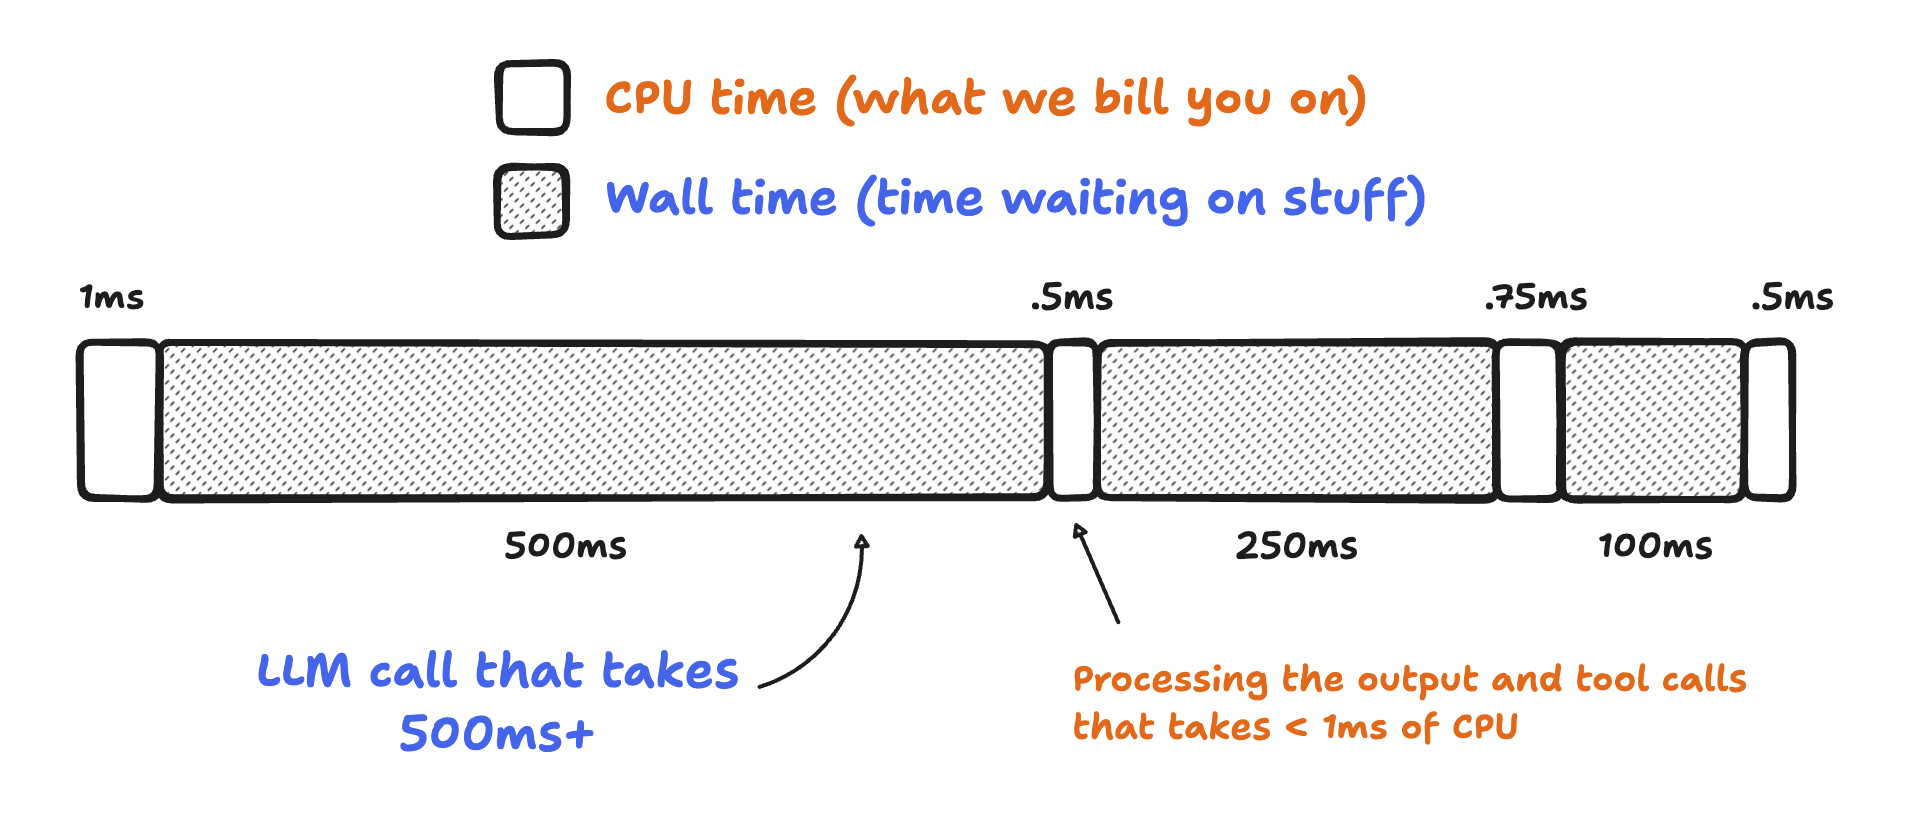
If you’re wondering what “CPU time” is here: it’s the time your Workflow is actively consuming compute resources. It doesn’t include time spent waiting on API calls, reasoning LLMs, or other I/O (like writing to a database). That might seem like a small thing, but in practice, it adds up: most applications have single digit milliseconds of CPU time, and multiple seconds of wall time: an API or two taking 100 – 250 ms to respond adds up!


Bill for CPU, not for time spent when a Workflow is idle or waiting.

Workflow engines, especially, tend to spend a lot of time waiting: reading data from object storage (like Cloudflare R2), calling third-party APIs or LLMs like o3-mini or Claude 3.7, even querying databases like D1, Postgres, or MySQL. With Workflows, just like Workers: you don’t pay for time your application is just waiting.

Start building

So you’ve got a good handle on Workflows, how it works, and want to get building. What next?

  1. Visit the Workflows documentation to learn how it works, understand the Workflows API, and best practices

  2. Review the code in the starter project

  3. And lastly, deploy the starter to your own Cloudflare account with a few clicks:

Introducing AutoRAG: fully managed Retrieval-Augmented Generation on Cloudflare

Post Syndicated from Anni Wang original https://blog.cloudflare.com/introducing-autorag-on-cloudflare/

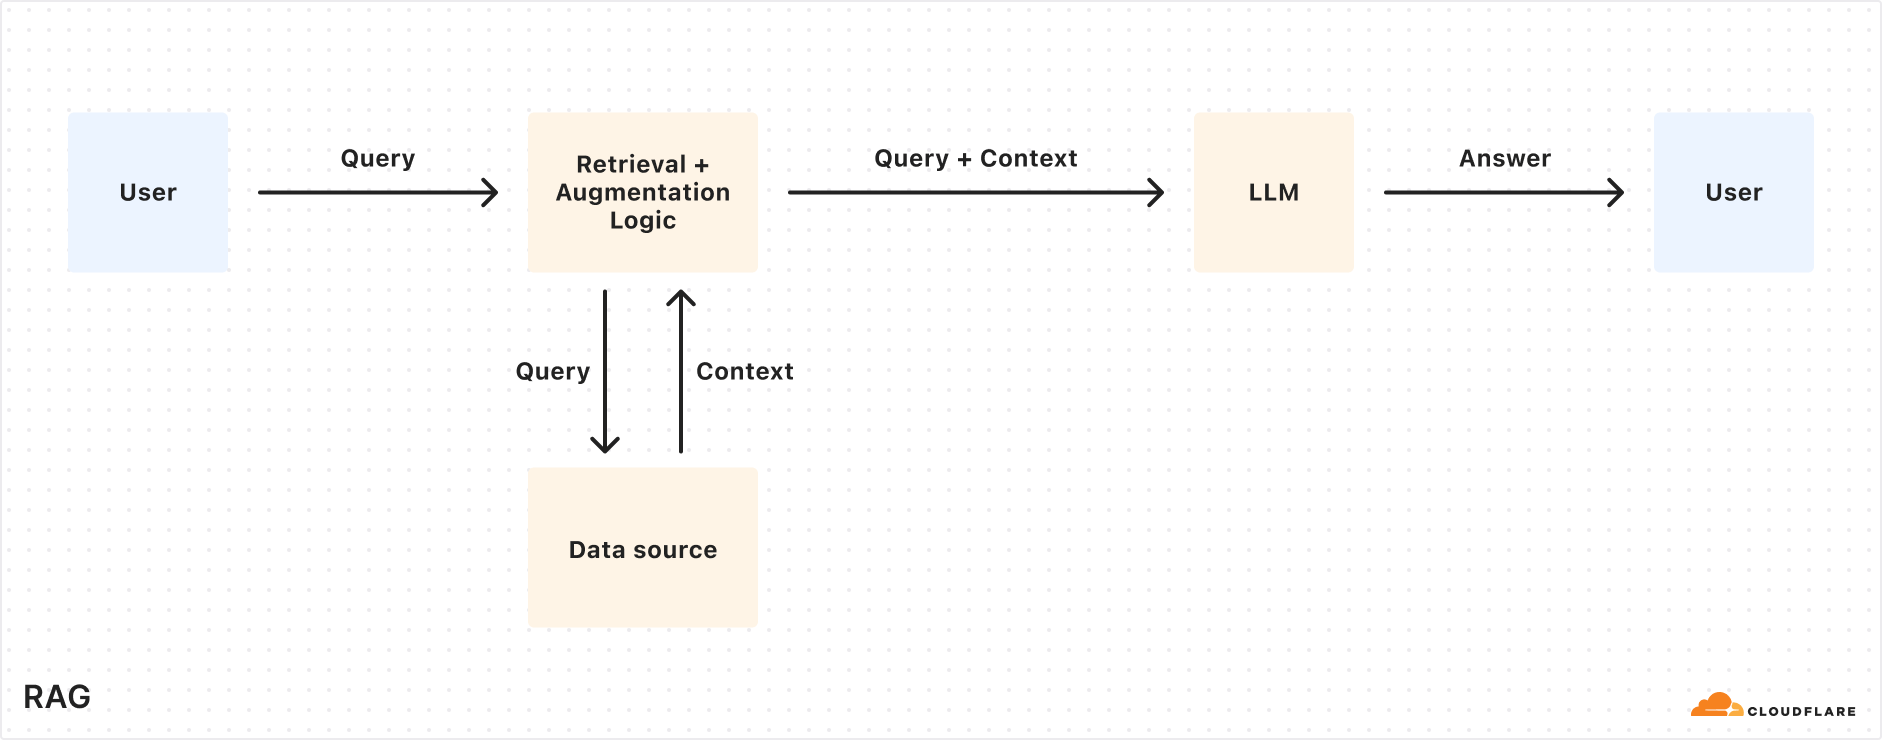
Today we’re excited to announce AutoRAG in open beta, a fully managed Retrieval-Augmented Generation (RAG) pipeline powered by Cloudflare, designed to simplify how developers integrate context-aware AI into their applications. RAG is a method that improves the accuracy of AI responses by retrieving information from your own data, and providing it to the large language model (LLM) to generate more grounded responses.

Building a RAG pipeline is a patchwork of moving parts. You have to stitch together multiple tools and services — your data storage, a vector database, an embedding model, LLMs, and custom indexing, retrieval, and generation logic — all just to get started. Maintaining it is even harder. As your data changes, you have to manually reindex and regenerate embeddings to keep the system relevant and performant. What should be a simple “ask a question, get a smart answer” experience becomes a brittle pipeline of glue code, fragile integrations, and constant upkeep.

AutoRAG removes that complexity. With just a few clicks, it delivers a fully-managed RAG pipeline end-to-end: from ingesting your data and automatically chunking and embedding it, to storing vectors in Cloudflare’s Vectorize database, performing semantic retrieval, and generating high-quality responses using Workers AI. AutoRAG continuously monitors your data sources and indexes in the background so your AI stays fresh without manual effort. It abstracts away the mess, letting you focus on building smarter, faster applications on Cloudflare’s developer platform. Get started today in the Cloudflare Dashboard!

Why use RAG in the first place?

LLMs like Llama 3.3 from Meta are powerful, but they only know what they’ve been trained on. They often struggle to produce accurate answers when asked about new, proprietary, or domain-specific information. System prompts providing relevant information can help, but they bloat input size and are limited by context windows. Fine-tuning a model is expensive and requires ongoing retraining to keep up to date.

RAG solves this by retrieving relevant information from your data source at query time, combining it with the user’s input query, and feeding both into the LLM to generate responses grounded with your data. This makes RAG a great fit for AI-driven support bots, internal knowledge assistants, semantic search across documentation, and other use cases where the source of truth is always evolving.


What’s under the hood of AutoRAG?

AutoRAG sets up a RAG pipeline for you, using the building blocks of Cloudflare’s developer platform. Instead of you having to write code to create a RAG system using Workers AI, Vectorize, and AI Gateway, you just create an AutoRAG instance and point it at a data source, like an R2 storage bucket.

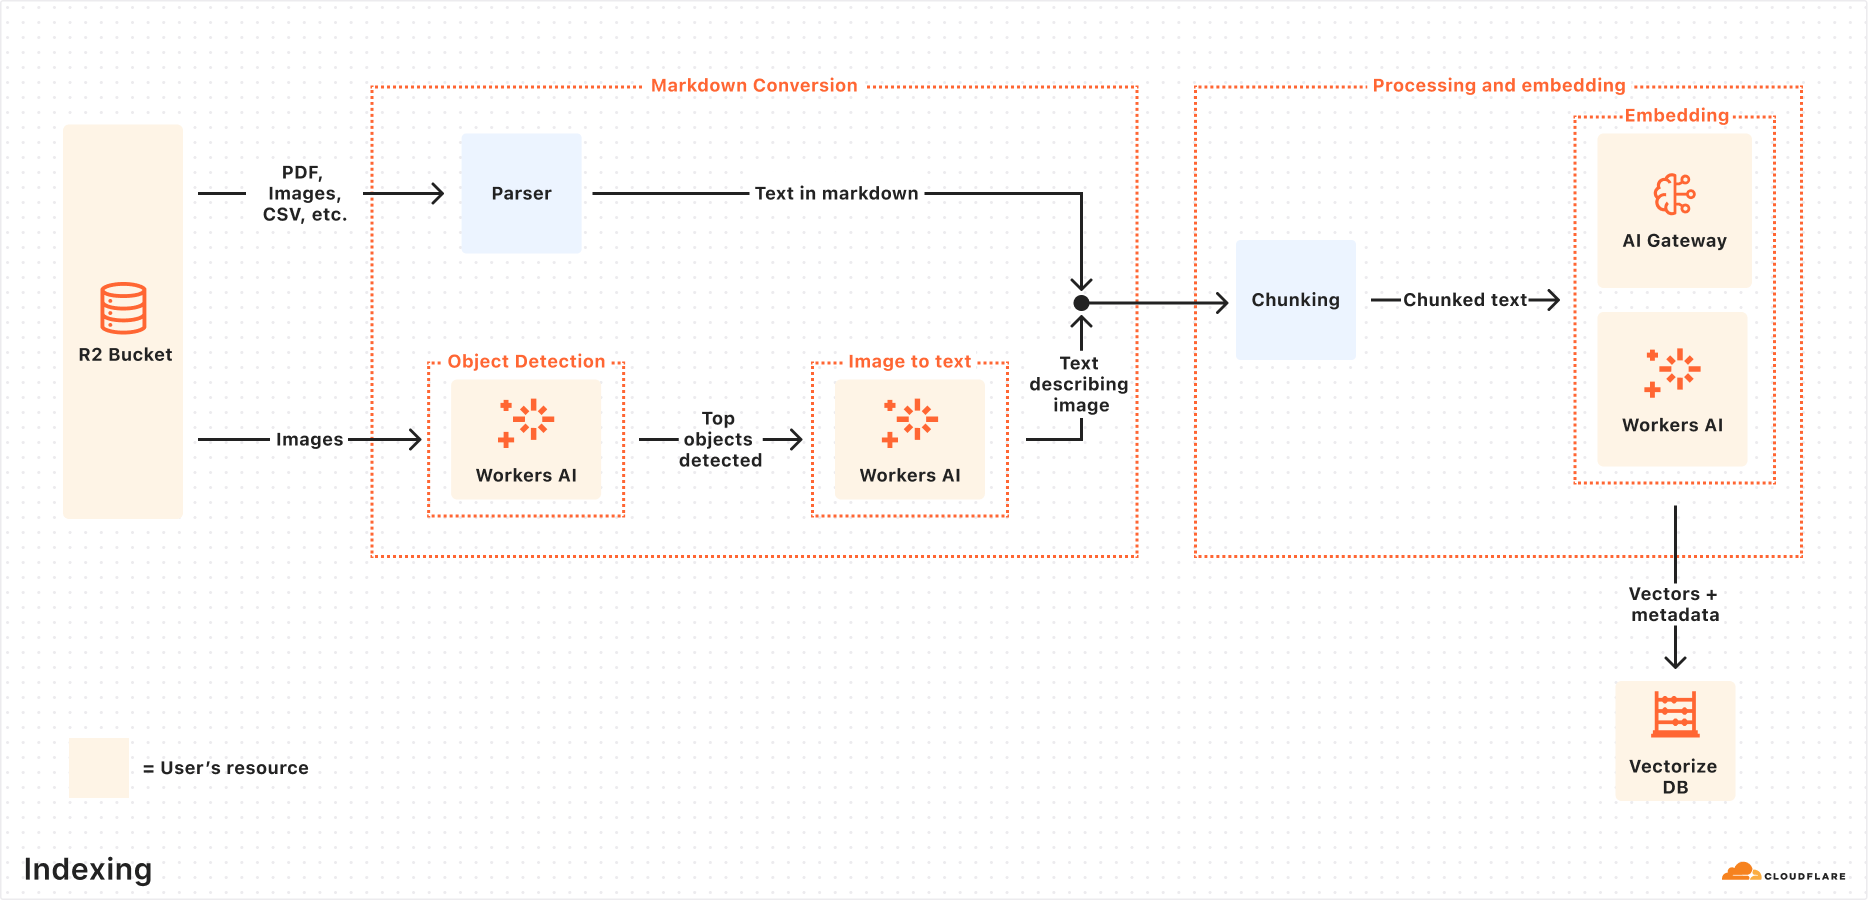
Behind the scenes, AutoRAG is powered by two processes: indexing and querying.

  • Indexing is an asynchronous process that runs in the background. It kicks off as soon as you create an AutoRAG, and automatically continues in cycles — reprocessing new or updated files after each previous job completes. During indexing, your content is transformed into vectors optimized for semantic search.

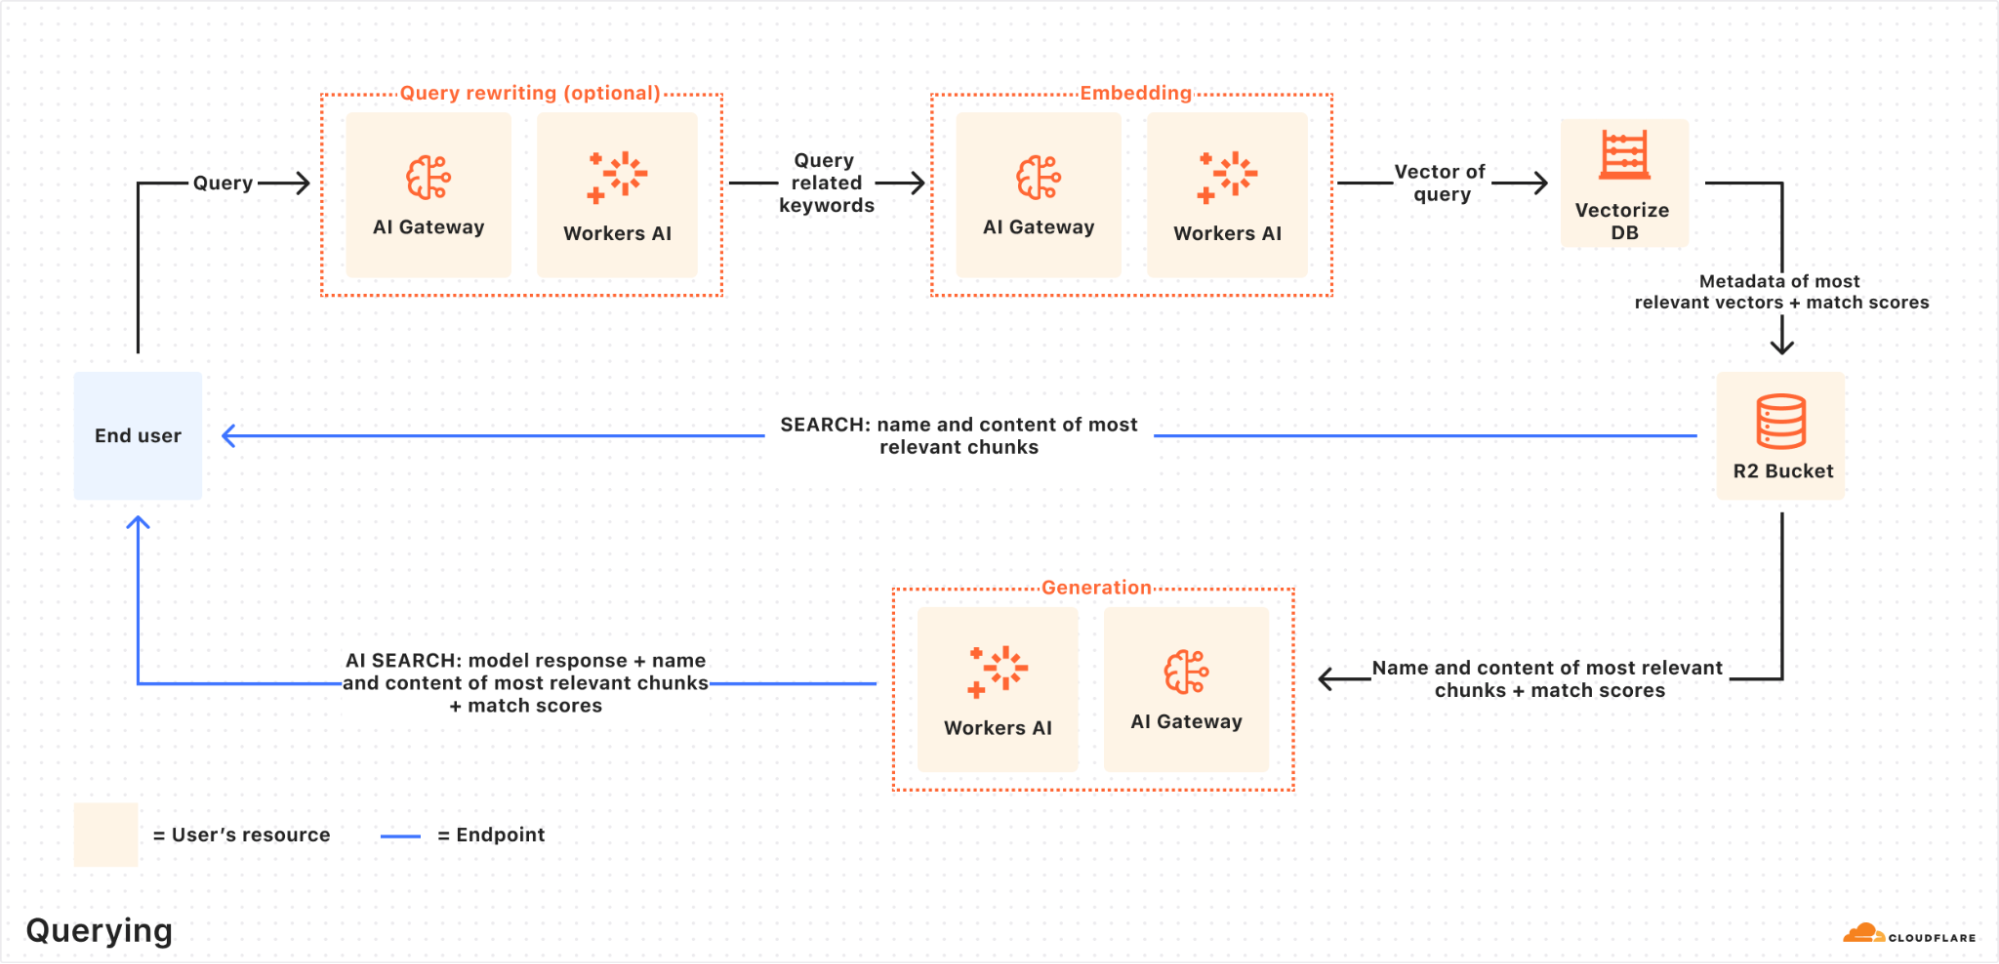
  • Querying is a synchronous process triggered when a user sends a search request. AutoRAG takes the query, retrieves the most relevant content from your vector database, and uses it to generate a context-aware response using an LLM.

Let’s take a closer look at how they work.

Indexing process

When you connect a data source, AutoRAG automatically ingests, transforms, and stores it as vectors, optimizing it for semantic search when querying:

  1. File ingestion from data source: AutoRAG reads directly from your data source. Today, it supports integration with Cloudflare R2, where you can store documents like PDFs, images, text, HTML, CSV, and more for processing.
    Check out the RAG to riches in 5 minutes tutorial below to learn how you can use Browser Rendering to parse webpages to use within your AutoRAG.

  2. Markdown conversion: AutoRAG uses Workers AI’s Markdown Conversion to convert all files into structured Markdown. This ensures consistency across diverse file types. For images, Workers AI is used to perform object detection followed by vision-to-language transformation to convert images into Markdown text.

  3. Chunking: The extracted text is chunked into smaller pieces to improve retrieval granularity.

  4. Embedding: Each chunk is embedded using Workers AI’s embedding model to transform the content into vectors.

  5. Vector storage: The resulting vectors, along with metadata like source location and file name, are stored in a Cloudflare’s Vectorize database created on your account.


Querying process

When an end user makes a request, AutoRAG orchestrates the following:

  1. Receive query from AutoRAG API: The query workflow begins when you send a request to either the AutoRAG’s AI Search or Search endpoint.

  2. Query rewriting (optional): AutoRAG provides the option to rewrite the input query using one of Workers AI’s LLMs to improve retrieval quality by transforming the original query into a more effective search query.

  3. Embedding the query: The rewritten (or original) query is transformed into a vector via the same embedding model used to embed your data so that it can be compared against your vectorized data to find the most relevant matches.

  4. Vector search in Vectorize: The query vector is searched against stored vectors in the associated Vectorize database for your AutoRAG.

  5. Metadata + content retrieval: Vectorize returns the most relevant chunks and their metadata. And the original content is retrieved from the R2 bucket. These are passed to a text-generation model.

  6. Response generation: A text-generation model from Workers AI is used to generate a response using the retrieved content and the original user’s query.

The end result is an AI-powered answer grounded in your private data — accurate, and up to date.


RAG to riches in under 5 minutes

Most of the time, getting started with AutoRAG is as simple as pointing it to an existing R2 bucket — just drop in your content, and you’re ready to go. But what if your content isn’t already in a bucket? What if it’s still on a webpage or needs to first be rendered dynamically by a frontend UI? You’re in luck, because with the Browser Rendering API, you can crawl your own websites to gather information that powers your RAG. The Browser Rendering REST API is now generally available, offering endpoints for common browser actions including extracting HTML content, capturing screenshots, and generating PDFs. Additionally, a crawl endpoint is coming soon, making it even easier to ingest websites.

In this walkthrough, we’ll show you how to take your website and feed it into AutoRAG for Q&A. We’ll use a Cloudflare Worker to render web pages in a headless browser, upload the content to R2, and hook that into AutoRAG for semantic search and generation.

Step 1. Create a Worker to fetch webpages and upload into R2

We’ll create a Cloudflare Worker that uses Puppeteer to visit your URL, render it, and store the full HTML in your R2 bucket. If you already have an R2 bucket with content you’d like to build a RAG for then you can skip this step.

  1. Create a new Worker project named browser-r2-worker by running:

npm create cloudflare@latest -- browser-r2-worker

For setup, select the following options:

  • What would you like to start with? Choose Hello World Starter.

  • Which template would you like to use? Choose Worker only.

  • Which language do you want to use? Choose TypeScript.

2. Install @cloudflare/puppeteer, which allows you to control the Browser Rendering instance:

npm i @cloudflare/puppeteer

3. Create a new R2 bucket named html-bucket by running: 

npx wrangler r2 bucket create html-bucket

4. Add the following configurations to your Wrangler configuration file, so your Worker can use browser rendering and your new R2 bucket:

{
	"compatibility_flags": ["nodejs_compat"],
	"browser": {
		"binding": "MY_BROWSER"
	},
	"r2_buckets": [
		{
			"binding": "HTML_BUCKET",
			"bucket_name": "html-bucket",
		}
	],
}

5. Replace the contents of src/index.ts with the following skeleton script:

import puppeteer from "@cloudflare/puppeteer";

// Define our environment bindings
interface Env {
	MY_BROWSER: any;
	HTML_BUCKET: R2Bucket;
}

// Define request body structure
interface RequestBody {
	url: string;
}

export default {
	async fetch(request: Request, env: Env): Promise<Response> {
		// Only accept POST requests
		if (request.method !== 'POST') {
return new Response('Please send a POST request with a target URL', { status: 405 });
		}

		// Get URL from request body
		const body = await request.json() as RequestBody;
		// Note: Only use this parser for websites you own
		const targetUrl = new URL(body.url); 

		// Launch browser and create new page
		const browser = await puppeteer.launch(env.MY_BROWSER);
		const page = await browser.newPage();

		// Navigate to the page and fetch its html
		await page.goto(targetUrl.href);
		const htmlPage = await page.content();

		// Create filename and store in R2
		const key = targetUrl.hostname + '_' + Date.now() + '.html';
		await env.HTML_BUCKET.put(key, htmlPage);

		// Close browser
		await browser.close();

		// Return success response
		return new Response(JSON.stringify({
			success: true,
			message: 'Page rendered and stored successfully',
			key: key
		}), {
			headers: { 'Content-Type': 'application/json' }
		});
	}
} satisfies ExportedHandler<Env>;

6. Once the code is ready, you can deploy it to your Cloudflare account by running:

npx wrangler deploy

7. To test your Worker, you can use the following cURL request to fetch the HTML file of a page. In this example we are fetching this blog page to upload into the html-bucket bucket:

curl -X POST https://browser-r2-worker.<YOUR_SUBDOMAIN>.workers.dev \
-H "Content-Type: application/json" \
-d '{"url": "https://blog.cloudflare.com/introducing-autorag-on-cloudflare"}'

Step 2. Create your AutoRAG and monitor the indexing

Now that you have created your R2 bucket and filled it with your content that you’d like to query from, you are ready to create an AutoRAG instance:

  1. In your Cloudflare dashboard, navigate to AI > AutoRAG

  2. Select Create AutoRAG and complete the setup process:

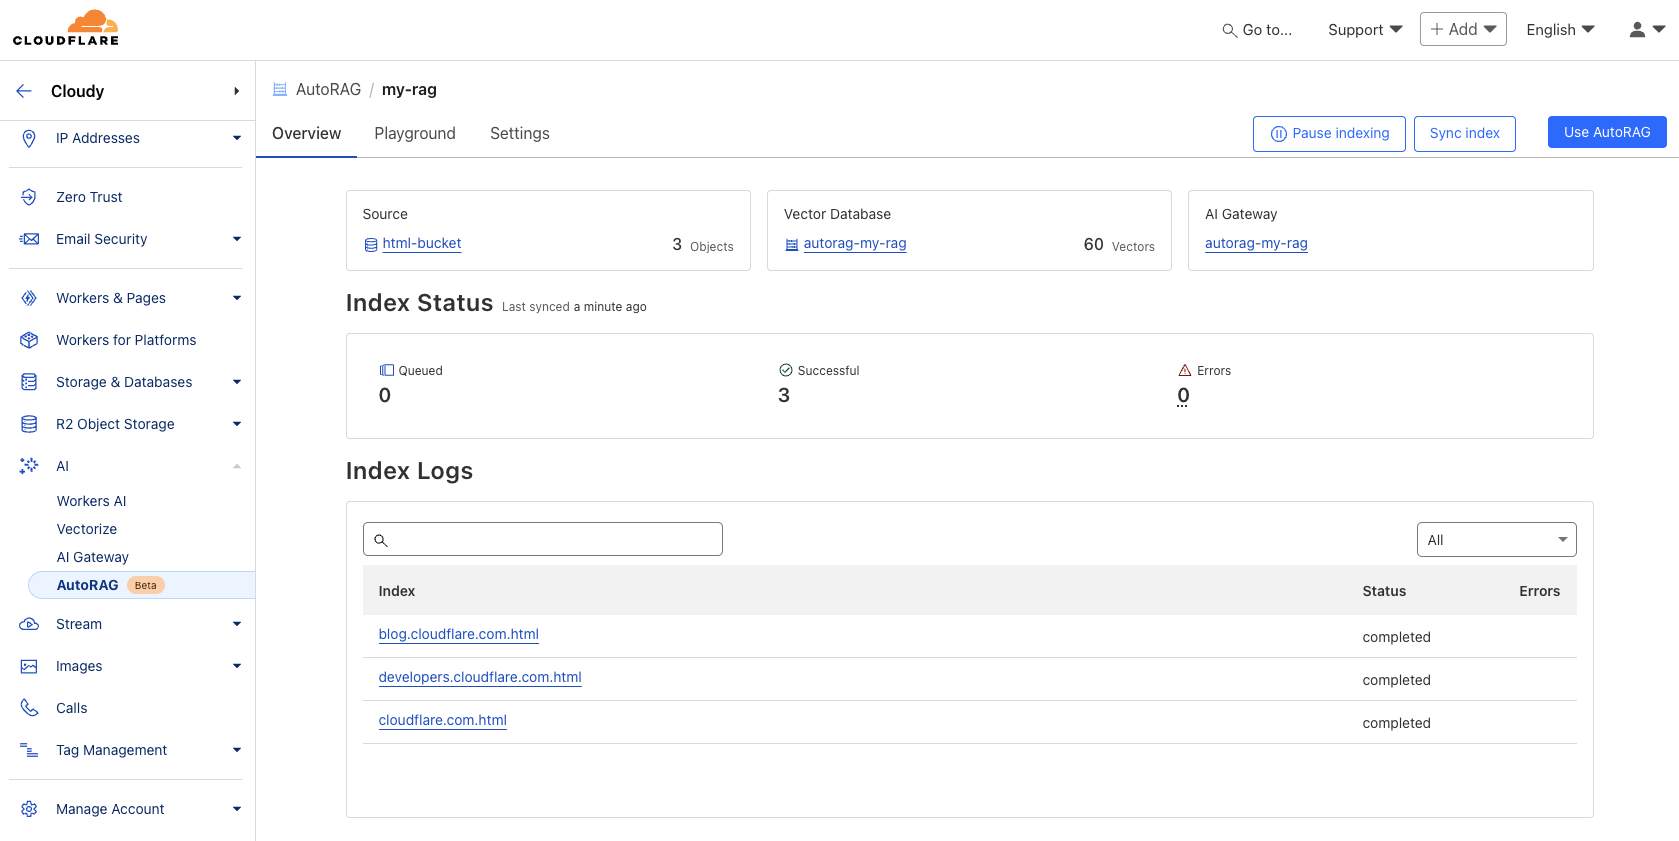
    1. Select the R2 bucket which contains your knowledge base, in this case, select the html-bucket.

    2. Select an embedding model used to convert your data to vector representation. It is recommended to use the Default.

    3. Select an LLM to use to generate your responses. It is recommended to use the Default.

    4. Select or create an AI Gateway to monitor and control your model usage.

    5. Name your AutoRAG as my-rag.

    6. Select or create a Service API token to grant AutoRAG access to create and access resources in your account.

  3. Select Create to spin up your AutoRAG.

Once you’ve created your AutoRAG, it will automatically create a Vectorize database in your account and begin indexing the data. You can view the progress of your indexing job in the Overview page of your AutoRAG. The indexing time may vary depending on the number and type of files you have in your data source.


Step 3. Test and add to your application

Once AutoRAG finishes indexing your content, you’re ready to start asking it questions. You can open up your AutoRAG instance, navigate to the Playground tab, and ask a question based on your uploaded content, like “What is AutoRAG?”.

Once you’re happy with the results in the Playground, you can integrate AutoRAG directly into the application that you are building. If you are using a Worker to build your application, then you can use the AI binding to directly call your AutoRAG: 

{
  "ai": {
    "binding": "AI"
  }
}

Then, query your AutoRAG instance from your Worker code by calling the aiSearch() method. Alternatively you can use the Search() method to get a list of retrieved results without an AI generated response.

const answer = await env.AI.autorag('my-rag').aiSearch({
   query: 'What is AutoRAG?'
});

For more information on how to add AutoRAG into your application, go to your AutoRAG then navigate to Use AutoRAG for more instructions.

Start building today

During the open beta, AutoRAG is free to enable. Compute operations for indexing, retrieval and augmentation incur no additional cost during this phase.

AutoRAG is built entirely on top of Cloudflare’s Developer Platform, using the same tools you’d reach for if you were building a RAG pipeline yourself. When you create an AutoRAG instance, it provisions and runs on top of Cloudflare services within your own account, giving you full visibility into performance, cost, and behavior with fewer black boxes.

These services include:

  • R2: stores your source data.

  • Vectorize: stores vector embeddings and powers semantic retrieval.

  • Workers AI: converts images to markdown, generates embeddings, rewrites queries, and generates responses.

  • AI Gateway: tracks and controls your model’s usage.

To help manage resources during the beta, each account is limited to 10 AutoRAG instances, with up to 100,000 files per AutoRAG. 

What’s on the roadmap?

We’re just getting started with AutoRAG and we have more planned throughout 2025 to make it more powerful and flexible. Here are a few things we’re actively working on:

  • More data source integrations: We’re expanding beyond R2, with support for new input types like direct website URL parsing (powered by browser rendering) and structured data sources like Cloudflare D1.

  • Smarter, higher-quality responses: We’re exploring built-in reranking, recursive chunking, and other processing techniques to improve the quality and relevance of generated answers.

These features will roll out incrementally, and we’d love your feedback as we shape what’s next. AutoRAG is built to evolve with your use cases so stay tuned.

Try it out today!

Get started with AutoRAG today by visiting the Cloudflare Dashboard, navigate to AI > AutoRAG, and select Create AutoRAG. Whether you’re building an AI-powered search experience, an internal knowledge assistant, or just experimenting with LLMs, AutoRAG gives you a fast and flexible way to get started with RAG on Cloudflare’s global network. For more details, refer to the Developer Docs. Also, try out the Browser Rendering API that is now generally available for your browser action needs.

We’re excited to see what you build and we’re here to help. Have questions or feedback? Join the conversation on the Cloudflare Developers Discord.

Security updates for Monday

Post Syndicated from jake original https://lwn.net/Articles/1016663/

Security updates have been issued by Debian (abseil, atop, jetty9, ruby-saml, tomcat10, trafficserver, xz-utils, and zfs-linux), Fedora (chromium, condor, containernetworking-plugins, cri-tools1.29, crosswords-puzzle-sets-xword-dl, exim, ghostscript, matrix-synapse, upx, varnish, and yarnpkg), Gentoo (XZ Utils), Mageia (augeas, corosync, nss & firefox, and thunderbird), Oracle (container-tools:ol8, firefox, freetype, and kernel), Red Hat (firefox), SUSE (chromium, gn, firefox-esr, go1.23-1.23.8, go1.24, go1.24-1.24.2, google-guest-agent, govulncheck-vulndb, gsl, python311-ecdsa, thunderbird, and webkit2gtk3), and Ubuntu (kamailio, libdbd-mysql-perl, linux-nvidia, linux-nvidia-6.8, and tomcat9).

Министерство на културата и НИНКН защитават вековната сграда История срещу печалба: Паметник на културата става жертва на кметска алчност

Post Syndicated from Екип на Биволъ original https://bivol.bg/pomorie-pametnik.html

понеделник 7 април 2025


Поморие е третият по големина български морски град. Последните 15 г. се управлява от ГЕРБ. Градът е особено важен за водещата партия, защото несменяемият му кмет Иван Алексиев оглавява и…

Материалът <span style='color:#ff0000;font-size:12px;'>Министерство на културата и НИНКН защитават вековната сграда</span> <BR> <H1 class='post-title single-post-title entry-title'>История срещу печалба: Паметник на културата става жертва на кметска алчност</H1> е публикуван за пръв път на Bivol!.

Don’t Miss Out: What You Need to Know Before Take Command 2025

Post Syndicated from Rapid7 original https://blog.rapid7.com/2025/04/07/dont-miss-out-what-you-need-to-know-before-take-command-2025/

Don’t Miss Out: What You Need to Know Before Take Command 2025

Take Command 2025 is just two days away, and there’s still time to secure your spot. Whether you’ve already registered or are building your agenda now, there’s plenty to look forward to — and it all starts this Wednesday, April 9.

In the lead-up to the live summit, two new on-demand sessions are already available for viewing, giving you a head start on key themes like attacker behavior and regulatory change. And during the event itself, you’ll get an exclusive look at findings from Rapid7’s latest ransomware research — pulled directly from Q1 threat activity and shared publicly for the first time.

This year’s event brings together top minds in cybersecurity for a full day of insights on exposure management, MDR, AI ,threat intelligence, red teaming, and more. It’s practical, high-impact content designed for practitioners, team leaders, and CISOs alike.

Hear the Latest Findings First at Take Command

If you want a pulse check on what’s happening across the threat landscape, don’t miss Inside the Mind of an Attacker: Navigating the Threat Horizon, led by Raj Samani, Chief Scientist at Rapid7.

Raj will be joined by Trent Teyema, Founder of CSG Strategies and former head of the FBI Cyber Division, for a panel that explores attacker methodologies, tactics, and trends. During the session, Raj will share key findings from Rapid7’s latest ransomware research, which will add depth to this important and insightful discussion. Attend this session and you’ll get a special research infographic and link to the detailed blog, which dives into

  • Which ransomware groups are most active in 2025 so far
  • How pressure tactics and extortion models are evolving
  • Which industries are being targeted — and why
  • What security teams can do now to reduce risk

Still Time to Register

There’s still time to register and experience Take Command 2025 as it happens. Attending live means you’ll:

  • Ask your questions during real-time Q&As
  • Hear fresh research and insights as they’re shared
  • Connect with experts and peers across the industry

This is your chance to be part of the conversation — not just watch it later. And if your schedule shifts? All sessions will be available on-demand after the event, so you can catch up at your convenience.

Get Ready to Take Command

Take Command 2025 brings together frontline experience, original research, and actionable guidance — all in one virtual event. If you haven’t registered yet, now is the time.

Whether you’re joining live, watching on-demand, or getting a head start with early sessions, this is your opportunity to learn what today’s threats really look like — and how to stay ahead of them.

Register now.

DIRNSA Fired

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/04/dirnsa-fired.html

In “Secrets and Lies” (2000), I wrote:

It is poor civic hygiene to install technologies that could someday facilitate a police state.

It’s something a bunch of us were saying at the time, in reference to the vast NSA’s surveillance capabilities.

I have been thinking of that quote a lot as I read news stories of President Trump firing the Director of the National Security Agency. General Timothy Haugh.

A couple of weeks ago, I wrote:

We don’t know what pressure the Trump administration is using to make intelligence services fall into line, but it isn’t crazy to worry that the NSA might again start monitoring domestic communications.

The NSA already spies on Americans in a variety of ways. But that’s always been a sideline to its main mission: spying on the rest of the world. Once Trump replaces Haugh with a loyalist, the NSA’s vast surveillance apparatus can be refocused domestically.

Giving that agency all those powers in the 1990s, in the 2000s after the terrorist attacks of 9/11, and in the 2010s was always a mistake. I fear that we are about to learn how big a mistake it was.

Here’s PGP creator Phil Zimmerman in 1996, spelling it out even more clearly:

The Clinton Administration seems to be attempting to deploy and entrench a communications infrastructure that would deny the citizenry the ability to protect its privacy. This is unsettling because in a democracy, it is possible for bad people to occasionally get elected—sometimes very bad people. Normally, a well-functioning democracy has ways to remove these people from power. But the wrong technology infrastructure could allow such a future government to watch every move anyone makes to oppose it. It could very well be the last government we ever elect.

When making public policy decisions about new technologies for the government, I think one should ask oneself which technologies would best strengthen the hand of a police state. Then, do not allow the government to deploy those technologies. This is simply a matter of good civic hygiene.

Introducing the quick start experience for Amazon Q Developer Pro

Post Syndicated from Matt Laver original https://aws.amazon.com/blogs/devops/introducing-the-quick-start-experience-for-amazon-q-developer-pro/

For software developers, development teams and IT Professionals, the Amazon Q Developer Pro Tier is recommended. The pro tier offers higher limits, enterprise administration, an analytics dashboard, code customizations and IP indemnity. In addition, the Amazon Q Developer Pro Tier requires AWS IAM Identity Center. For most production deployments, an organization instances of IAM Identity Center is recommended. An organization instance supports identity aware sessions which are required to use the Pro tier in the AWS Console, in addition to the benefits outline in the IAM identity Center user guide.

However, what if your team would like to get started quickly to try out Amazon Q Developer Pro Tier on the IDE but there are constraints that are slowing you down such as:

  • You don’t have plans to adopt IAM Identity Center across your organization.
  • You have an organization instance of IAM Identity Center, but you want to deploy Amazon Q Developer Pro to an isolated set of users that are distinct from users in your organization instance.
  • You don’t control the AWS Organization in which you operate. For example, a third-party controls the AWS organization that manages your AWS accounts and it takes time to get changes approved.

To address these scenarios, we recently announced a new, simplified setup experience with two steps that makes it easier for teams that are looking to try out the features of Amazon Q Developer Pro in their Integrated Development Environment (IDE).

Management Account and AWS IAM Identity Center

Before we jump into a tour of the quick start setup, let’s take a step back and consider the AWS recommendation of using a multi-account setup to organize your workloads. The benefits can be seen in our AWS white paper on organizing Your AWS Environment Using Multiple Accounts and the recommended approach is to implement this with AWS Organizations. A management account is the AWS account you use to create your organization and this should be kept minimal and secure and only host essential administrative tools such as setting up AWS Organizations and implementing single sign on via IAM Identity Center.

IAM Identity Center is core to the Amazon Q Developer Pro setup. IAM Identity Center users can access AWS accounts and applications using their existing organizational credentials, without the need to create and manage separate AWS accounts and passwords.

For example, IAM Identity Center can connect and automatically provision users from standards-based identity providers including Microsoft Active Directory, Okta, Microsoft Entra ID, Google Workspace or another supported identity provider (IdP) via Security Assertion Markup Language (SAML) 2.0 or OIDC.

Manage Access to Amazon Q Developer via AWS IAM Identity Center

Figure 1. Manage Access to Amazon Q Developer via AWS IAM Identity Center.

This is a great experience for developers as they simply authorize their Q Developer session with their usual sign in process via the Identity source already in place in their business. Administrators benefit from features such as centralized access management, streamlined permissions management and enhanced administrator capabilities to view Amazon Q user activity.

Amazon Q Developer Pro Simplified Setup Experience

The above approach of setting up IAM Identity Center in a management account is ideal but not always viable, so we have created a new getting started experience makes it easier for teams that are looking to try out the features of Amazon Q Developer Pro in their Integrated Development Environment (IDE) starting with:

  • A standalone account that is not part of an organization managed by AWS Organizations.
  • A member account, other than the management account, that is part of an AWS Organization but doesn’t have organization level users managed in IAM Identity Center.

For both standalone and member accounts there is a two step process. The first step for setting up Amazon Q Developer Pro starts by navigating to the Amazon Q console and selecting Get started:

Amazon Q Console - Getting started with Amazon Q

Figure 2. Amazon Q Console – Getting started with Amazon Q.

The setup will guide through creating the first user and activating a subscribing to Amazon Q Developer Pro in your account, this initial step also includes creating an account instance of IAM Identity Center and an AWS managed application instance of Amazon Q Developer. A detailed walkthrough is available in our documentation – Subscribing users to Amazon Q Developer Pro.

When complete, the first user can be seen within the Amazon Q Subscriptions:

Amazon Q Subscriptions.

Figure 3. Amazon Q Subscriptions.

The second step is to subscribe the additional team members to the account instance of IAM Identity Center and then subscribing them to Amazon Q Developer Pro via the Amazon Q console.

IAM Identity Center Users

Figure 4. IAM Identity Center Users.

Once a user has been successfully subscribed, they will receive an email with instructions on how to activate their Amazon Q Developer Pro Subscription and start using the features.

Note that account instances of IAM Identity Center have limitations. For example, account instances don’t support console access. (Users can still use Amazon Q in the console, it’s just that they’ll be subject to the Free tier monthly limits.) If you want to use Amazon Q Developer Pro in the console and other AWS websites, you must be a user in an organization instance of IAM Identity Center, in a management account.

At this point, it should be noted, that IAM Identity Center can now be configured to change it’s identity source to a Federated Identity Provider (IdP), see our documentation pages on how to change your identity source.

Cleanup

To cleanup the resource created in this blog, first remove Amazon Q Developer Pro users by following our guide:

Secondly, delete the IAM Identity Center instance:

Conclusion

Getting started with Amazon Q Developer Pro is now even easier with the new, simplified setup experience, you can experience the pro features in your IDE such as higher limits on advanced features such as:

  • Chat, debug code, add tests and more in your integrated developer environment (IDE).
  • Accelerate tasks with the Amazon Q Developer agents for software development.
  • Upgrade apps in a fraction of the time with the Amazon Q Developer Agent for code transformation.

Get on-board with the Amazon Q Developer User Guide on Subscribing users to Amazon Q Developer Pro.

Read more about how the community are using Amazon Q to write code and build applications faster and easier with Amazon Q on community.aws and explore what we are building with Amazon Q Developer here.

Note that while this post focuses on Amazon Q Developer Pro, developers can get started at no cost and without an AWS account; Amazon Q Developer offers a perpetual Free Tier with monthly limits available to users, see our user guide for Amazon Q Developer Free tier.

About the author:

Matt Laver

Matt Laver is a Senior Specialist Solutions Architect at Amazon Web Services (AWS) with a focus on Developer Experience. He is passionate about helping customers find simple solutions to difficult problems.

Hello World #26 out now: Digital Literacy

Post Syndicated from Meg Wang original https://www.raspberrypi.org/blog/hello-world-26-out-now-digital-literacy/

We often believe we understand the meaning of ‘digital literacy’, but it can be a misleading term. Do we mean digital skills? Online safety? Where does AI fit in? As computer science education evolves to meet the needs of our increasingly digital world, we believe that true digital literacy empowers young people to engage with technology thoughtfully, critically, and confidently.

In this issue of Hello World, out today for free, we discuss what digital literacy means, how it is taught in different countries around the world, and how educators are rethinking digital literacy for their students and themselves.

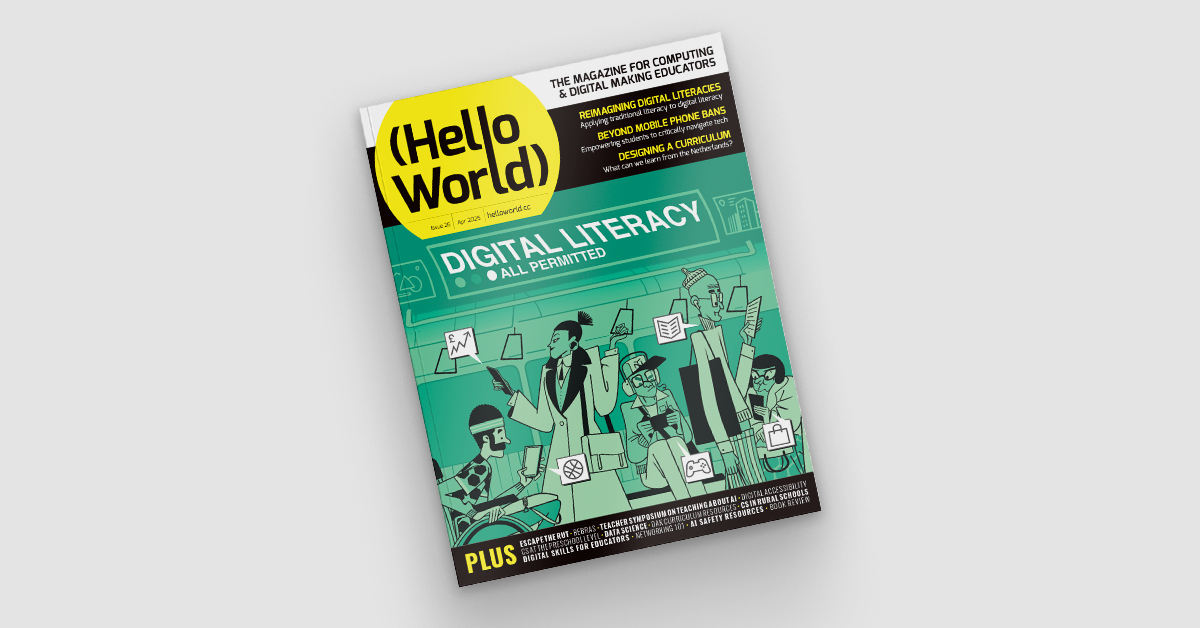
Digital image of Hello World, issue 26 'digital literacy' displayed at an angle.

Digital literacy

As the use of digital technology grows, a broader view of digital literacy is necessary. Digital literacy is more than knowing how to use software. It’s the ability to use digital technologies effectively, safely, and responsibly.

In Issue 26 of Hello World, we explore this topic in detail and hear insights from educators across the world, including:

  • Becci Peters shares how Computing at School (CAS) in the UK is supporting digital literacy skills for students and educators
  • Sourav Pattanayak discusses how digital literacy is defined in India, and the formal and informal ways educators are teaching digital literacy
  • Sandra Hartman explores strategies for enhancing digital literacy in the US
  • Gavin Davenport asks what would happen if we considered digital literacy in the same way as we consider traditional literacy
Photo of young people sitting at a desk, working on small computers.

This issue also includes inspiring articles from the world of computer science education:

  • Leah Dungay tells us about a programme combining physics, video games, and the Large Hadron Collider to engage young people in particle physics 
  • Gina Fugate shares how digital accessibility enhances digital experiences for all
  • Halima Bhayat shares her inspiring journey in computer science

And there is lots more for you to discover in issue 26.

New podcast series in audio and video

We’re also pleased to announce that the Hello World podcast has returned alongside the magazine with a miniseries also focused on digital literacy.

We asked for your thoughts on the podcast in our previous annual survey, and you kindly sent us lots of helpful feedback. Based on that, we’re trialling new episode formats, welcoming additional hosts, and bringing in more expert voices from around the world.

On Tuesday 15 April we’ll be releasing our first teacher tips episode, a shorter podcast with 3 teachers sharing practical, actionable tips for improving digital literacy in the classroom. 

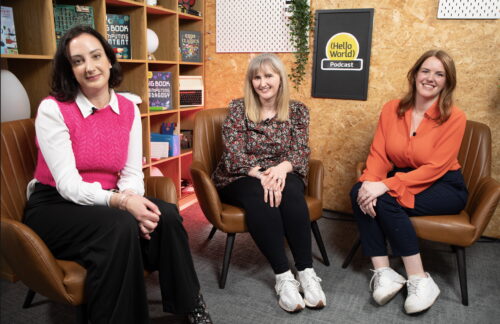
Image featuring Dr. Jessica Hamer, Becky Patel and Rachel Arthur after recording an episode of the Hello World podcast.

The week after, Tuesday 22 April, you’ll be able to hear a brilliant conversation between the Raspberry Pi Foundation’s Chief Learning Officer, Rachel Arthur, and two special guests: Dr Jessica Hamer from King’s College London’s School of Education and Becky Patel from Tech She Can. They’ll be discussing the current state of girls’ engagement in computing — a wide-reaching and important conversation exploring how we can empower more girls in computing through school, university and their careers.

Then on Tuesday 29 April the final episode in the miniseries will be a panel debate about “digital natives” where we’ll be asking, ‘Are young people who grew up with technology around them truly tech-savvy, or are they dependent on digital tools without understanding how they work?’ James Robinson — Senior Learning Manager here at the Raspberry Pi Foundation and regular host of the podcast — will lead this discussion as global educators debate the myth of the “digital native,” uncover how it could overlook complex issues of access, skills, and education, and consider what it really takes to be tech-smart in the modern world.

More information and links to listen can be found inside the magazine.

Share your thoughts & subscribe to Hello World

We hope you enjoy this issue of Hello World, and please get in touch with your article ideas or what you would like to see in the magazine.

  • Share your thoughts and ideas about Hello World and the new issue with us via the Raspberry PI Foundation social media channels
  • Find out how you can write for the magazine

Subscribe to Hello World for free to never miss an issue.

The post Hello World #26 out now: Digital Literacy appeared first on Raspberry Pi Foundation.

Политика, просвета и провал. Кой се страхува от американските университети?

Post Syndicated from Яна Хашъмова original https://www.toest.bg/politika-prosveta-i-proval-koy-se-strahuva-ot-amerikanskite-universiteti/

Политика, просвета и провал. Кой се страхува от американските университети?

Ако сте имали юноши вкъщи или сте наблюдавали поведението им сред близки семейства, със сигурност знаете, че този период от развитието на личността се характеризира с чести промени в мисленето и вземането на решения. От личен опит мога да кажа, че често, вместо да споря със сина си предпочитам да изчакам до следващия ден, когато вече сам е променил мнението си.

Юношеството се отличава с егоцентрични и нарцистични нагласи, докато индивидът не премине в зрелостта. Тогава личностите проявяват повече разбиране към околните, анализират ситуациите в тяхната сложност и нюанси и са склонни да търсят причините за неуспешни междуличностни отношения не само в другите, но и в себе си.

Базирайки се на практиката си и на други изследвания, психоложката Марго Уадел¹ обобщава: 

Тийнейджърът може да бъде сътрудничещ в един момент, непокорен в следващия, неспособен лесно да признае, че този, който се е заел със задачата, и този, който не е успял да я изпълни, са едно и също лице, а именно самият той.

Може да се посочат още много примери за поведението на юношите, но проблемът възниква, когато някои не успяват да надраснат импулсивността и други поведенчески нагласи на юношеството и те останат да ги следват през целия им живот.

Вероятно вече откривате връзката със ставащото в политиката на САЩ напоследък. „Юношеското поведение“ на Доналд Тръмп и администрацията му е едновременно забавно за наблюдение и много тревожно. В продължение на четири години той отричаше изборните резултати, заменяйки реалността с лъжи – типична характеристика на юношеството. А през последните два месеца колко пъти обяви и отмени митата за Мексико и Канада? Колко пъти заплаши с прекратяване на държавни помощи и грантове за образование и научни изследвания само за да ги спира временно или по-скоро да заплашва с прекратяването им, докато университетите не се съгласят с промени? Дори издаде указ за закриване на Министерството на образованието, но закриването е сложно, защото за подобно действие е нужно одобрение от Конгреса, което е малко вероятно. 

Политика, просвета и провал. Кой се страхува от американските университети?
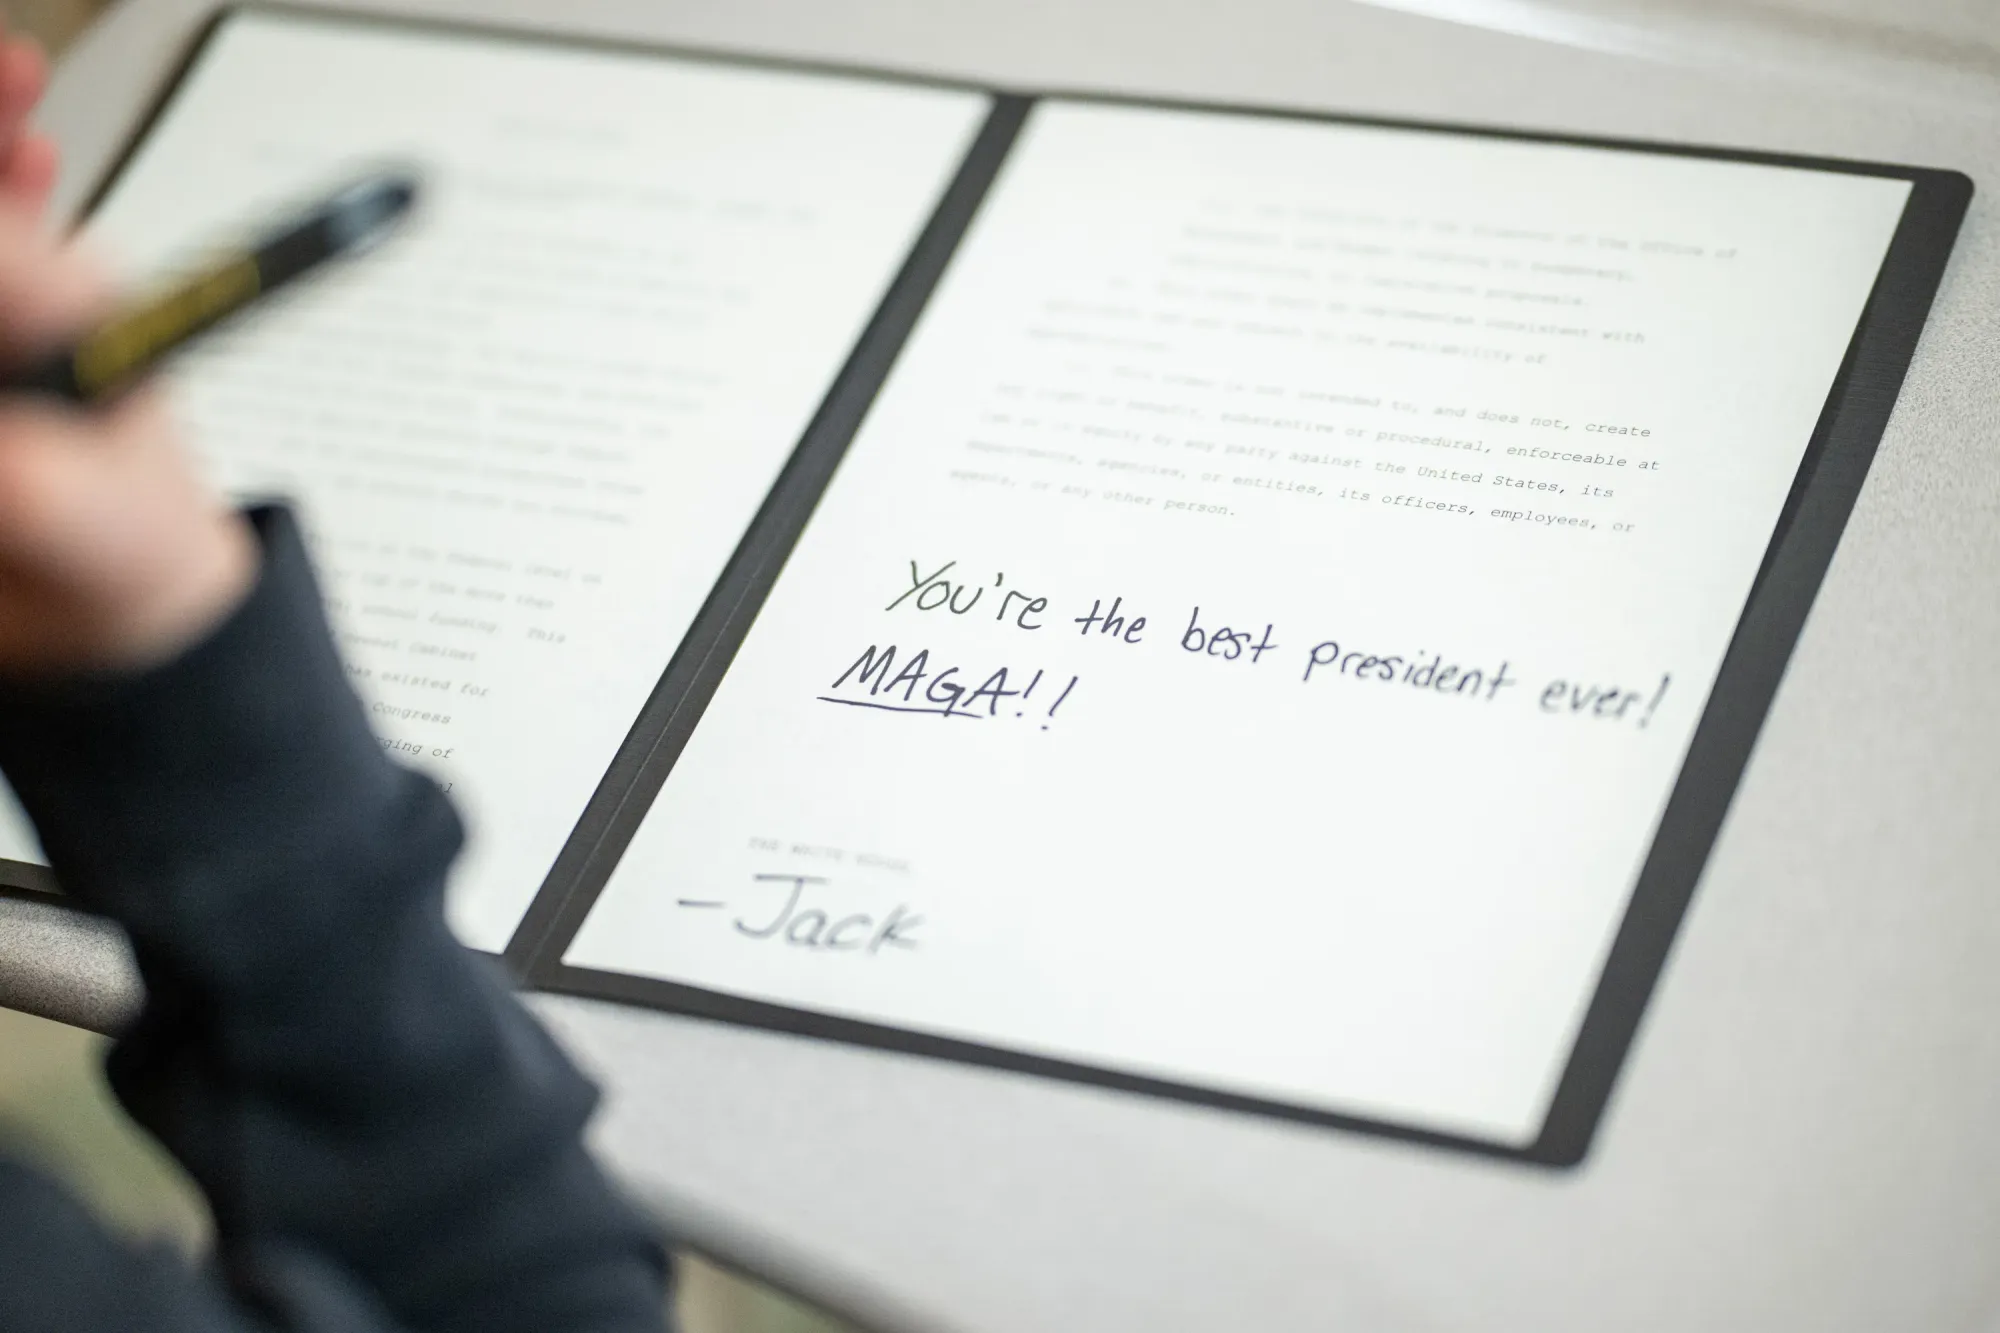
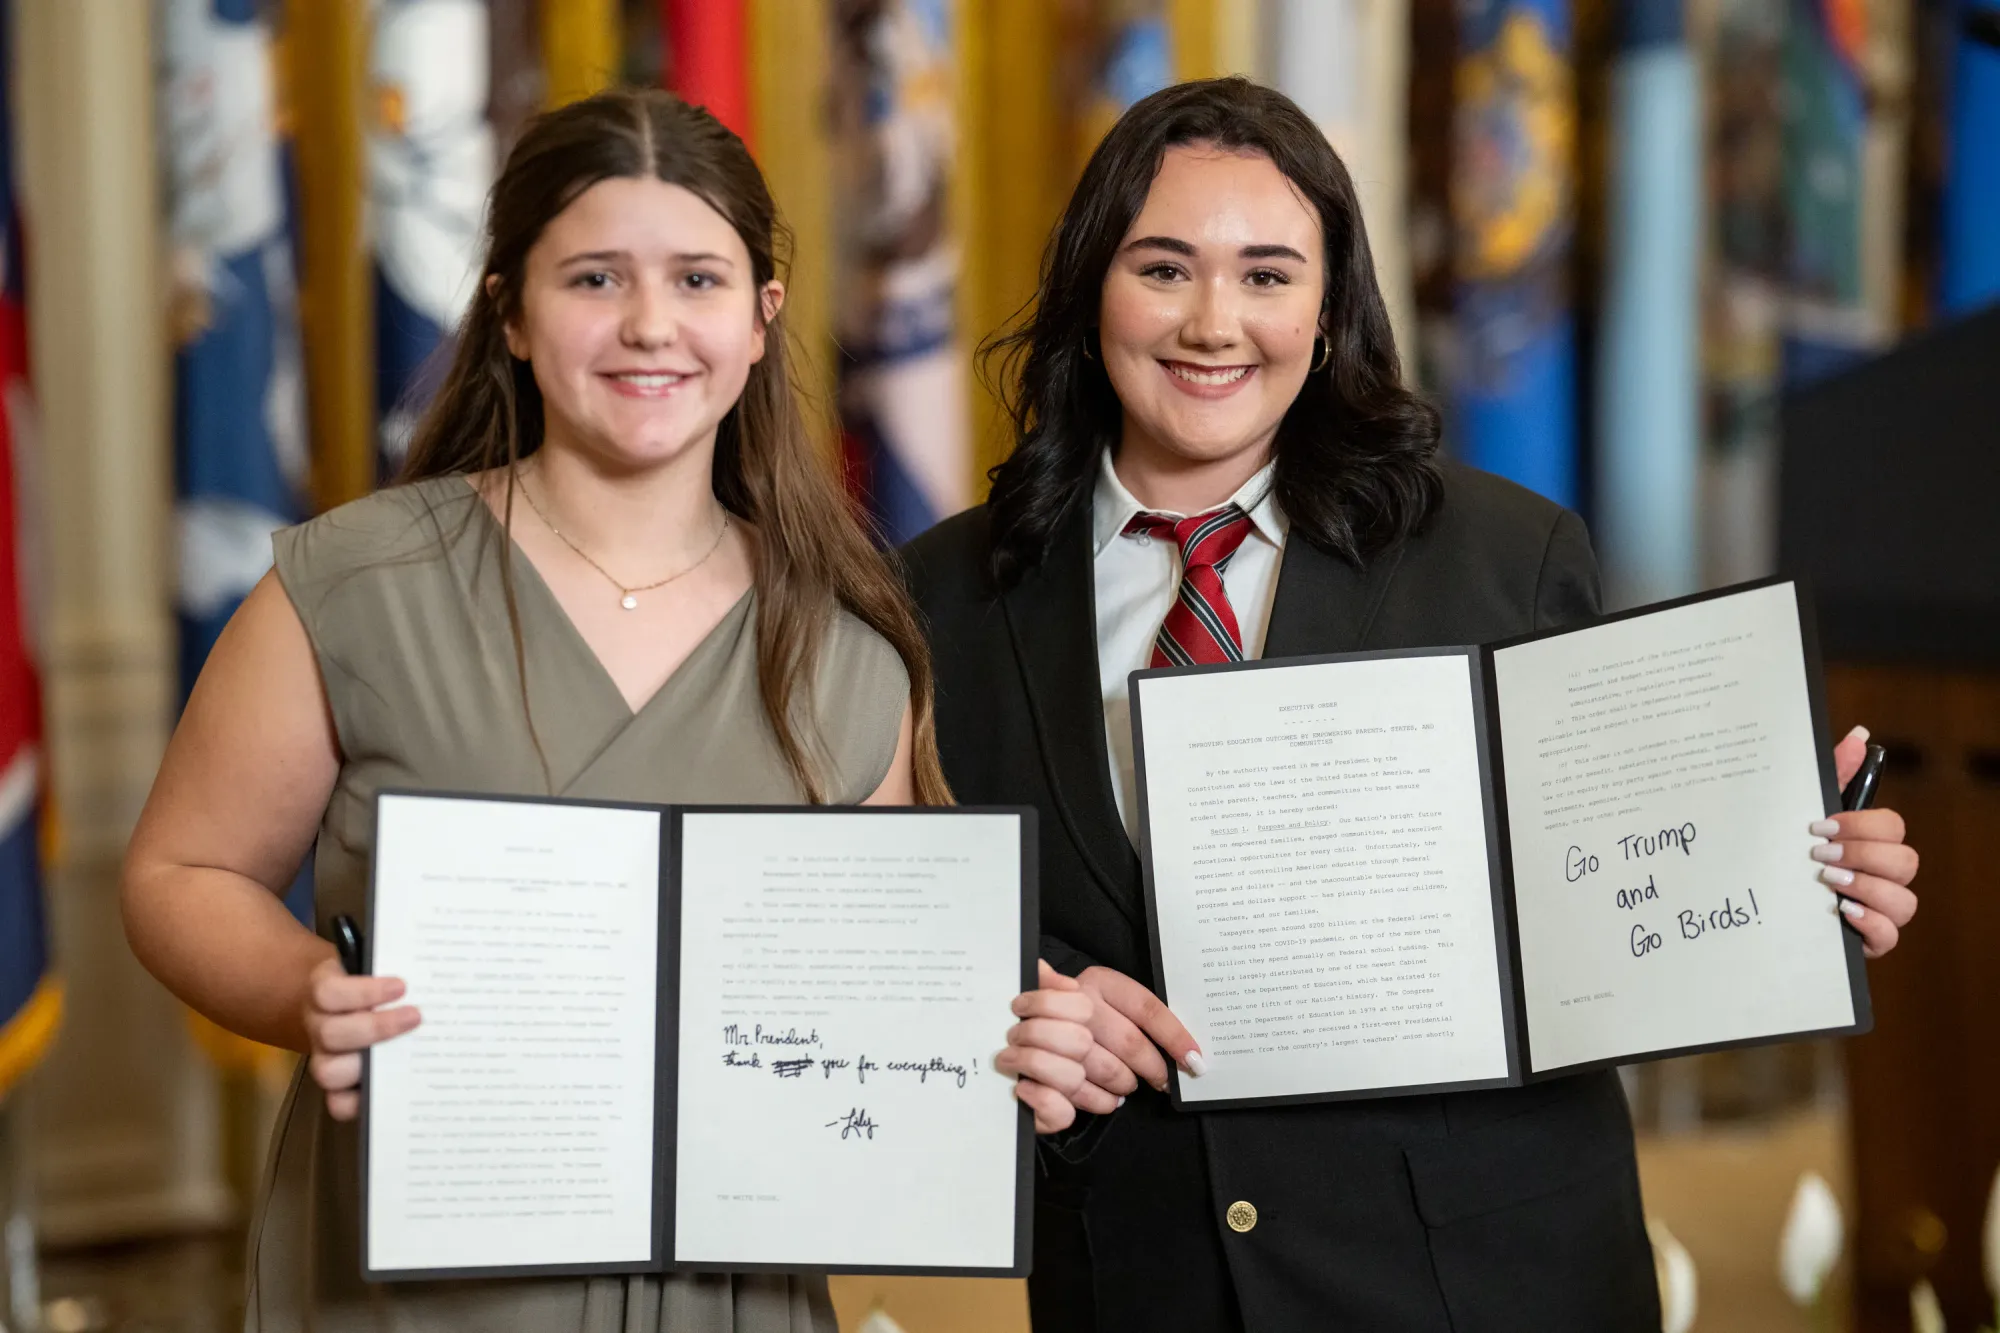
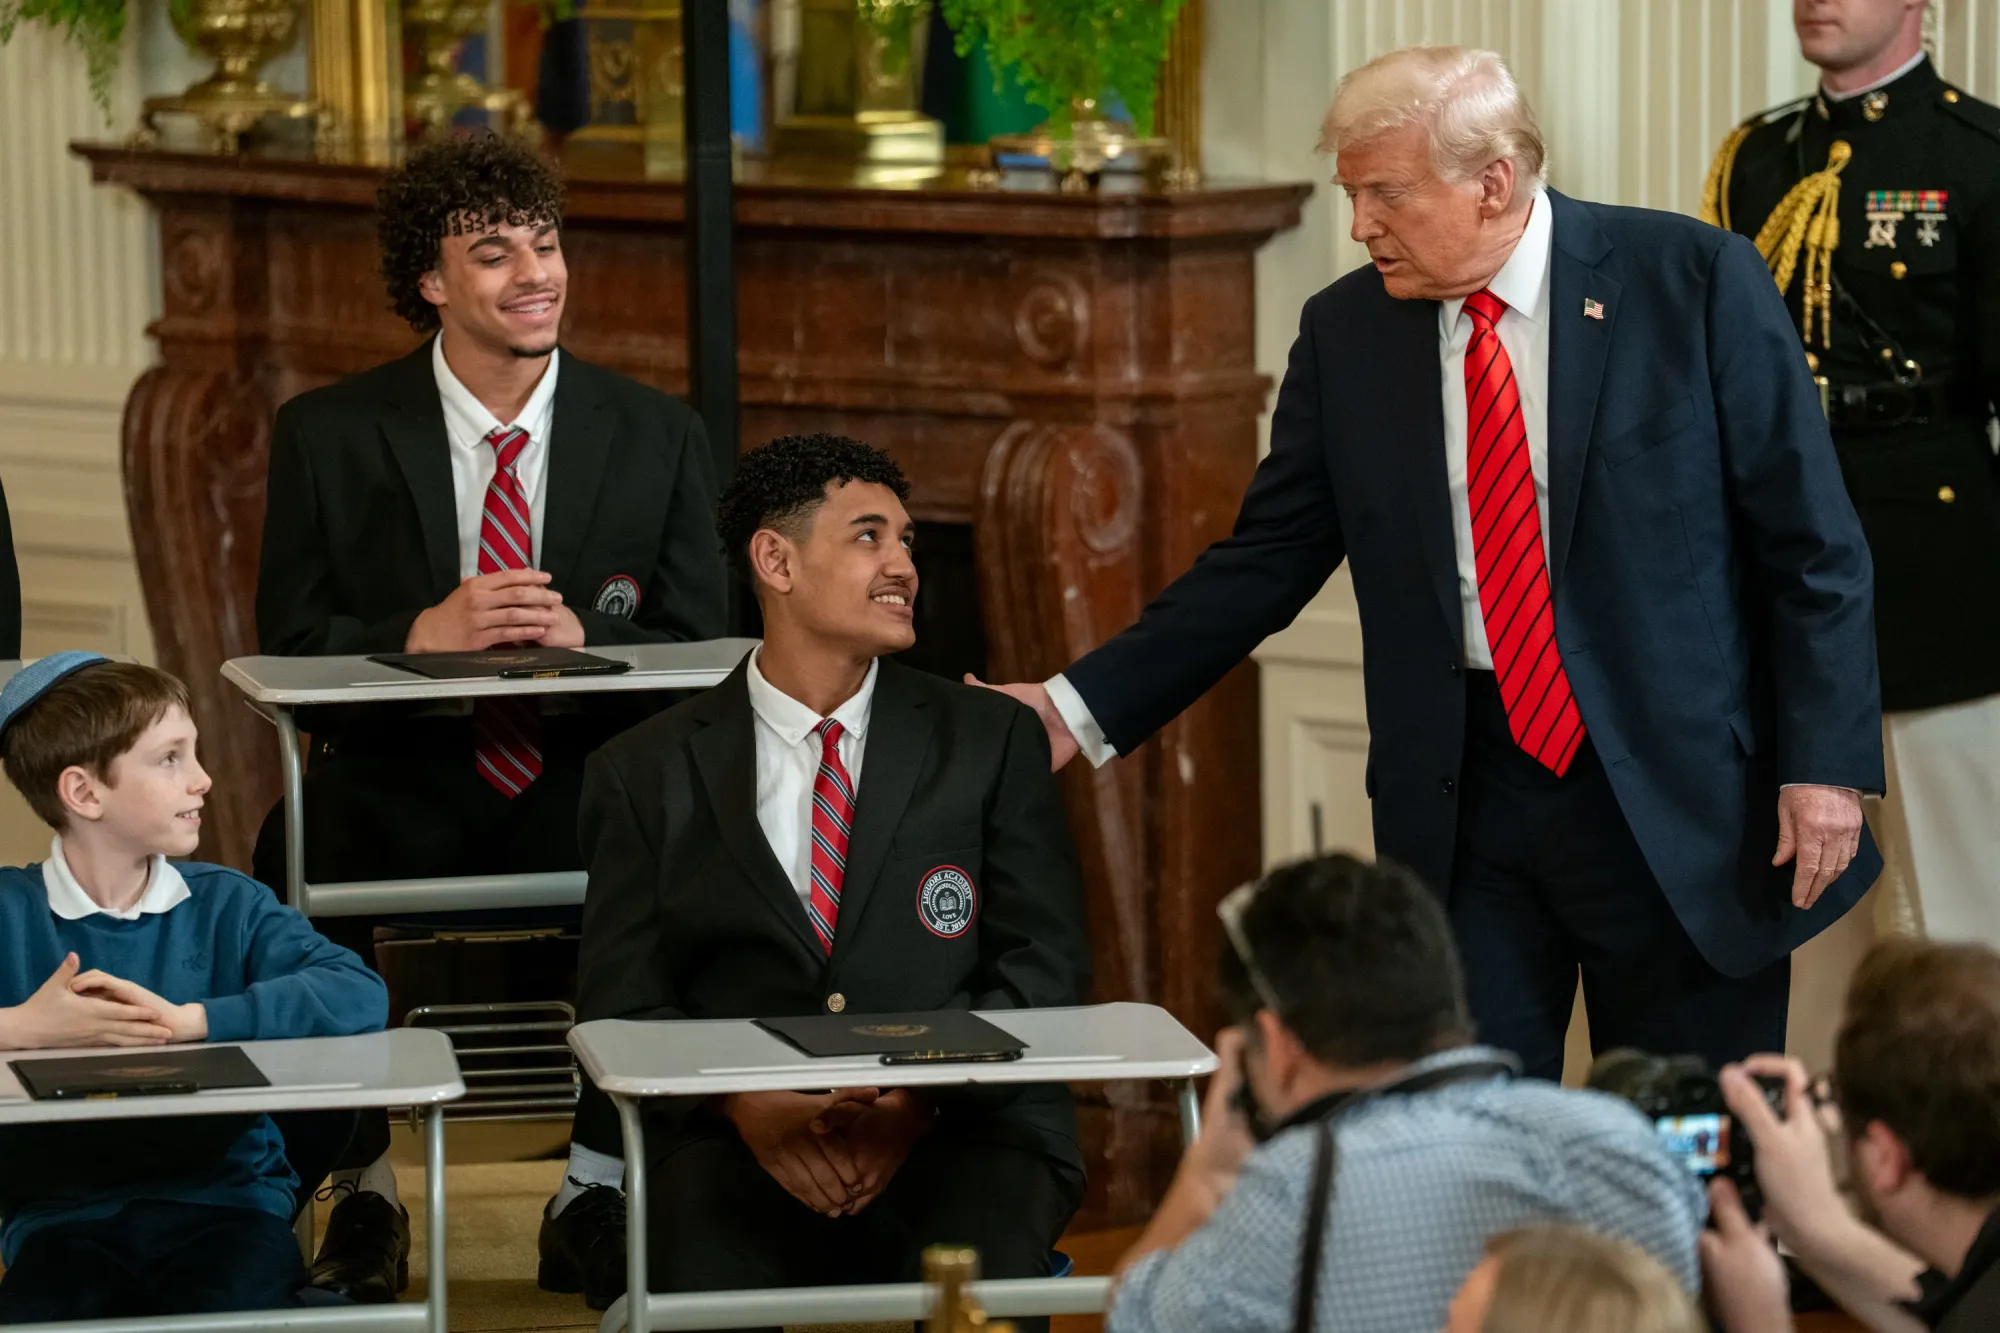
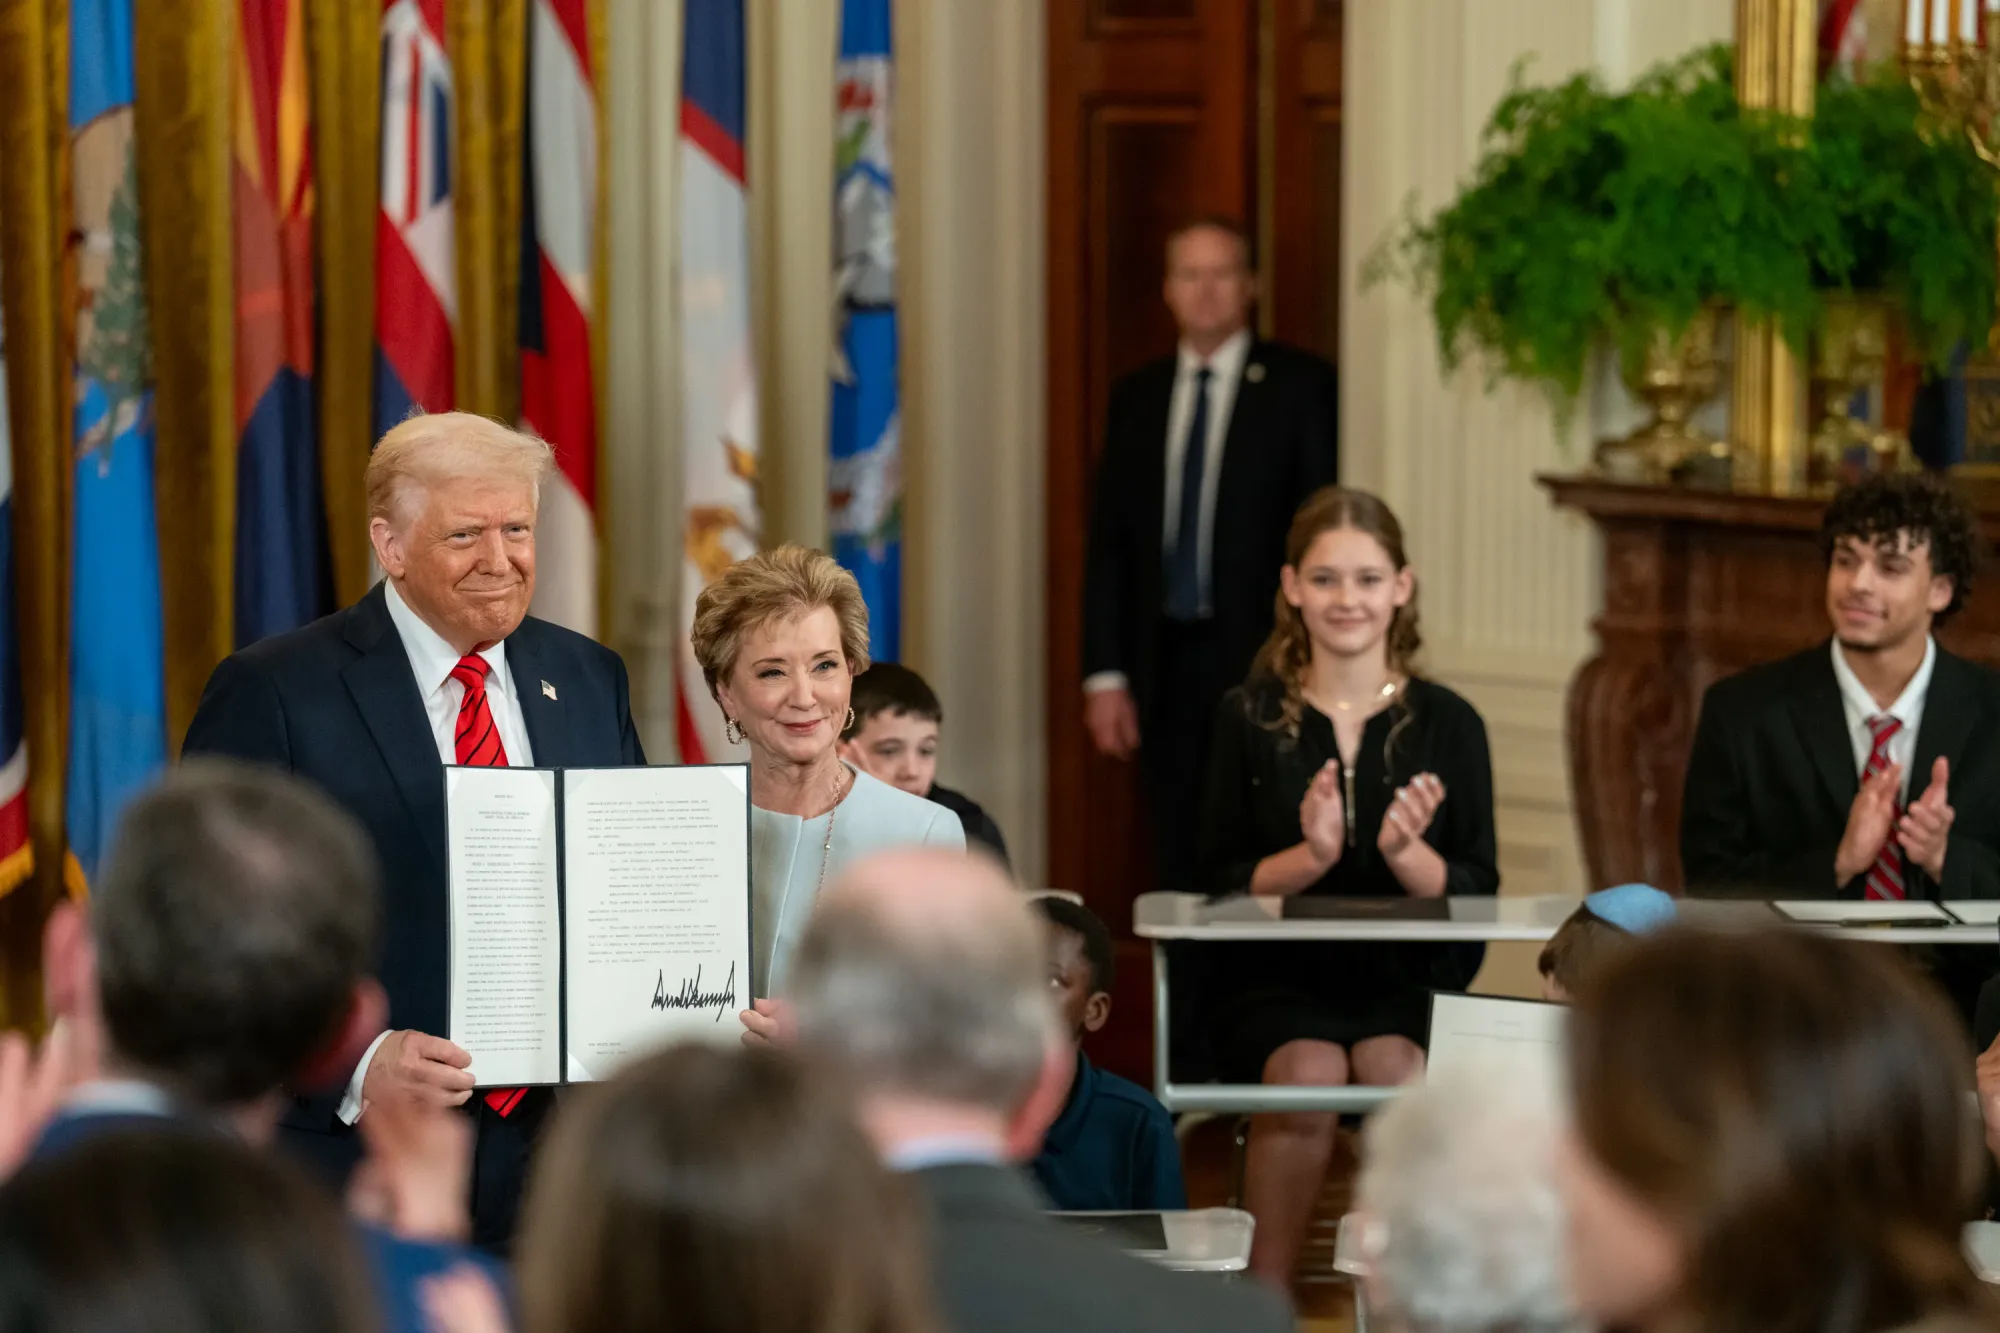
По време на подписването на заповедта за закриването на Министерството на образованието президентът Тръмп беше заобиколен от ученици, които подписваха същия документ, но с пожелания към президента. Снимка: The White House

Едно министерство по-малко

В специално съобщение министърката на образованието Линда Макмахън твърди, че президентският указ за закриване на Министерството е исторически, защото ще овласти отделните щати и родителите да се грижат за образованието на децата. Макмахън добавя и важна подробност – че ще работи в условията на закона и с Конгреса. Де факто дейността на Министерството ще бъде намалена и някои програми ще се прикачат към други министерства. А действителното му закриване засега е под въпрос. 

Тези стъпки бяха предприети, защото според администрацията на Тръмп Министерството не е вършило добра работа в последните години. Това според консерваторите би следвало да означава, че всякаква образователна дейност за защитата на разнообразието и равенството прекрачва границите и възпрепятства свободата на словото. В същото време обаче имиграционните власти арестуваха студента Махмут Халил при липсата на каквoто и да е незаконно действие от негова страна и при положение че той е законен жител на САЩ, заради „престъплението“ да оглави пропалестински протести в кампуса на Колумбийския университет. Може да се запитаме кой и как прекрачва границите на свободата на словото. 

Важно е да се обърне внимание, че още преди провеждането на президентските избори Джей Ди Ванс апелира да се атакуват университетите като места, на които се проповядват „заблуди и лъжи, не и истината“ и които са затворени за консервативни идеи.

Ако някой от нас изобщо иска да постигне нещата, които сме решили, за нашата държава и за хората, които живеят в нея, трябва откровено и агресивно да атакуваме университетите в страната.

Оказва се, че университетите заплашват статуквото и са опасни. 

За да се намали влиянието на научните изследвания и съответно на прогреса и развитието на образованието, през последните три месеца в университетите непрекъснато постъпва информация за отменени щатски образователни фондове, като всяко следващо съобщение противоречи на предишното. Самата аз като преподавател получавам такива съобщения. Ето цитат от последното относно правителствен грант: 

За да ви дам малко повече контекст – през януари получихме заповед за спиране на работата. През февруари получихме заповед за прекратяване. През март заповедта за спиране на работата беше отменена, но уведомленията не се отнасяха за заповедта за прекратяване. В момента се опитваме да изясним дали отмяната на заповедта за спиране на работата означава и отмяна на заповедта за прекратяване. 

Политика, просвета и провал. Кой се страхува от американските университети?
Снимка: The White House

Забавление, хаос или провал?

Интересно е, че атаките срещу висшите училища идват от Ванс и Тръмп, и двамата с дипломи от елитни частни университети. И в тези атаки, и в последвалите действия се крие много по-голяма заплаха за демокрацията и свободата на словото в САЩ, отколкото може би се долавя на пръв поглед. 

Юношеското поведение и подменената реалност могат да бъдат изключително деструктивни и опасни. Идеологическите приоритети на правителството и атаките срещу университетите бързо се възприемат от отделни щатски администрации. В Охайо, където преподавам, Конгресът на щата прие закон, който напомня за държавната намеса в образованието в България по време на социализма. Законът ограничава академичната свобода, като забранява преподаването и обсъждането на „противоречиви убеждения или политики“, сред които са климатичните промени, изборната политика, имиграцията, въпросите на многообразието и равенството и дори бракът. Освен това в закона е добавено изискването университетите да декларират, че преподавателите и служителите им ще позволят на студентите да стигнат до свои собствени заключения по горепосочените теми и няма да се опитват да „индоктринират“ студентите. 

И макар, както казах, това да напомня за времената у нас, когато образованието трябваше да следва партийната линия, тогава със сигурност нямаше чак такъв хаос. Забраната за преподаване на противоречиви теми е даже по-ограничаваща от социалистическата цензура. А що се отнася до индоктринирането, може би е добре да се запитаме кому са нужни необразовани и немислещи граждани и гласоподаватели. По този повод изразих мислите си преди време пак в „Тоест“. 

Политика, просвета и провал. Кой се страхува от американските университети?
Снимка: The White House

Истината е, че студентите трябва да стигат до собствени заключения, но те следва да са основани на факти, доказателства и научни изследвания. Няма как в дисциплините по природни науки например студентите да следват убежденията си за креационизма или да се уповават на християнското разбиране за създаването и развитието на човечеството.

Страх, пари и консервативна политика

Страховете на републиканците от университети и колежи като място на прогресивни идеи не са новост и не започват с идването на Тръмп на власт. Преди две години Сенатът на Охайо, изцяло управляван от Републиканската партия, отдели 24 млн. долара от щатския бюджет за създаването на центрове за „интелектуално разнообразие“ в пет университета, включително в Държавния университет на Охайо. Под „интелектуално разнообразие“, изглежда, следва да се разбира развитието на консервативни нагласи и мнения. Например директорът на Центъра „Чейз“ в Държавния университет на Охайо, назначен през лятото на 2024 г., е конституционалист, който държи на тълкуването на американската Конституция, както са я написали и разбирали създателите ѝ преди два века. През годините стана ясно, че по подобен начин я тълкуват консервативни съдии във Върховния съд, като покойния вече Антонин Скалия, Ейми Барет, Кларънс Томас, Нийл Горсъч, които, освен че поддържат други ретроградни позиции, отхвърлят правото на аборт и правото на еднополовите двойки да сключват брак. 

Въпреки че висшето учебно заведение е задължено да изпълни условията, заложени в бюджета на щата Охайо относно създаването на академични центрове, и въпреки че директорът на Центъра „Чейз“ вече беше назначен, все пак трябваше да се мине през университетската процедура за откриването на център или катедра. Малко абсурдно, като в романите на Кафка, новоназначеният директор трябваше да напише подробно предложение, което да се разгледа в комисии.

Последната стъпка от процедурата изискваше Сенатът на Държавния университет на Охайо, състоящ се от преподаватели, административни служители и студенти, да гласува. Гласуването се проведе след изслушването на мнения, сред които силно се открои изказването на студент от специалността „Обществени науки“, който аргументирано обясни, че създаването на този център противоречи на всичко, което е учил в курсовете си. Вотът, въпреки че е само символичен, беше отрицателен, целящ да регистрира протест срещу политическото и държавното вмешателство в работата на университета. 

Политика, просвета и провал. Кой се страхува от американските университети?
Президентът Тръмп и министърката на образованието Линда Макмахън позират с прясно подписаната заповед за закриване на Министерството на образованието. Снимка: The White House

Усилията за доказване на несъвместимостта на сенатския закон 1 с академичната свобода и целите на образованието продължават. Гласува се и резолюция срещу закона от Съвета на преподавателите към Сената на университета. Всичко това не попречи на губернатора да подпише указа. А как точно ще се прилага, е загадка. Какви ще са материалните загуби за университетите, засега също остава неясно. 

Единствената идеология, която може да се окаже по-силна от консервативната политика, е тази на парите – университетските администрации вече изчисляват какви финансови щети ще нанесе този закон. Забраната за преподаването на „противоречиви“ теми ще затрудни университетите. Но в закона са предвидени и други ограничения, например забрана за научно сътрудничество с Китай. 

Последствията засега са действително непредвидими. Преди три години Държавният университет на Охайо промени структурата на задължителните общообразователни предмети и създаде теми (образователна категория – б.р.) като „Гражданство за справедлив и разнообразен свят“ и „Расово, етническо и джендър разнообразие“. Ако спрем да водим тези курсове, студентите няма да могат да завършат образованието си, защото няма да са изпълнили задължителните елементи от програмата си. И това важи за стотици курсове и за около 60 000 студенти. 

Стратегия в хаоса 

Анализатори определят поведението на Тръмп като стратегия за създаване на хаос, която не позволява на демократите да отправят ясно послание. На някои този хаос им напомня „Хамлет“ на Шекспир, където Полоний, наблюдавайки привидно хаотичното поведение на Хамлет, отбелязва: 

Че е лудост – лудост е, но има система в нея!…²

Дори да приемем, че поведението на Тръмп е стратегия, не може да се отрече, че подобен подход вреди на икономиката и външната политика на САЩ. Войната в Украйна не приключи за обещаните 24 часа, инфлацията не намаля осезаемо, стоковата борса се срина, а заплахите с митата не дават сигурни резултати. Тръмп също се проваля с обещаните масови изселвания на незаконни имигранти, като в същото време отклонява вниманието на електората си със символични действия (например ареста на Махмут Халил), които прекрачват конституционните му правомощия. А предложението му за импийчмънт на съдия бе категорично отхвърлено от председателя на Върховния съд Джон Робъртс. Да не споменаваме множеството съдебни процеси, които се водят и ще се водят и които могат да забавят доста от очакваните промени, обещани в предизборната му кампания. 

Големите обещания на Тръмп изглеждат все по-неустойчиви. Както казва Марго Уадел, „този, който се е заел със задачата, и този, който не е успял да я изпълни, са едно и също лице, а именно самият той“. Една дълбоко противоречива и проблематична личност, различна от трагичния Хамлет. И докато все още е рано да се правят заключения за ефективността на хаоса, сегашните резултати са далеч от първоначално заявените „светкавични промени“ – обещания, породени от юношески деструктивни фантазии, наранена гордост и нарцисизъм. А аз с удоволствие ще се върна на този въпрос след четири години.

1 Inside Lives: Psychoanalysis and the Growth of the Personality, p. 135.

2 „Хамлет“, превод Валери Петров.

Kernel prepatch 6.15-rc1

Post Syndicated from corbet original https://lwn.net/Articles/1016577/

Linus has released 6.15-rc1 and closed the
merge window for this release. “As expected, this was one of the bigger
merge windows, almost certainly just because we had some pent-up
development due to the previous releases being impacted by the holiday
season. That said, while it’s bigger than normal, it’s not some kind of
record-breaking thing.
“. In the end, 12.633 non-merge changesets were
pulled into the mainline during this merge window.

The collective thoughts of the interwebz