Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=BPcQKb1hlbM
Enhancing Code Generation with Real-Time Execution in Amazon Q Developer
Post Syndicated from Sundaresh Iyer original https://aws.amazon.com/blogs/devops/enhancing-code-generation-with-real-time-execution-in-amazon-q-developer/
As AI continues to drive rapid innovation in software development, a reliable runtime environment for real-time testing is essential to promote high-quality code generation. Developers often face delays in feature delivery as they spend significant time debugging and iterating on AI-generated code to verify it meets project requirements. Previously, the Amazon Q Developer development agent focused on code generation. With its latest update, the agent can now build and test code in real time, validating changes before a developer’s review. This new capability directly addresses community feedback regarding code recommendation quality, detecting errors, keeping generated code in sync with the project’s current state, and accelerating the development process by streamlining both code generation and testing workflows.
With natural language input and project-specific context, the Amazon Q Developer agent is designed to assist in implementing complex multi-file features, bug fixes, and test suites. For example, a developer can request Amazon Q Developer agent to add a checkout feature to an e-commerce application. The agent then analyzes the existing codebase, makes all necessary code changes and tests within minutes, including running any unit tests and building the code to verify the code is ready for review. This approach significantly improves development efficiency and reduces errors. To use the Amazon Q Developer agent in your IDE, simply install the Amazon Q extension and use the /dev command in the chat window to initiate requests.
Once the /dev command is entered in the IDE, the agent packages the project and securely uploads it to Amazon Q, initiating project-specific code generation. The Amazon Q Developer agent not only focuses on code generation, but also maintains a real-time connection with the developer, providing updates throughout the process and delivering a polished patch or implementation for the requested feature.
This real-time execution is powered by a Devfile, which defines the development environment and commands the agent can use. If a project doesn’t already have a Devfile, Amazon Q Developer will prompt users to create one after their first run of /dev. Without a Devfile, the agent will develop solutions without the additional feedback provided by running builds or unit tests, limiting developers’ ability to receive real-time feedback during the development process.
Core enhancements in the latest Amazon Q Developer update
- Customizable Commands: Developers can specify commands in a Devfile to control which commands the AI agent runs, reducing unnecessary steps and improving accuracy.
- Flexible Environment Setup: Developers can use custom Docker images preloaded with dependencies for faster startup times, providing the agent has all necessary tools.
- Sandboxed Security: Amazon Q Developer secures the execution within isolated environments, offering comprehensive logging and robust permission controls to safeguard any changes made.
With this setup, Amazon Q Developer can execute tests, apply migrations, and run installation commands directly within a sandbox, providing feedback to the agent for iterative improvements.
Security and isolation
Given the security-sensitive nature of executing AI-generated code, the Amazon Q Developer agent introduces several safeguards:
Environment Isolation: Commands are executed within an isolated, managed sandbox environment configured without credentials to access non-public internet resources, ensuring that only authorized actions are performed securely.
Devfile driven: This feature requires a Devfile, and the Devfile configuration allows developers to control which commands the agent uses during the development process.
Getting started with the Amazon Q Developer agent
To get started, you need to have an AWS Builder ID or be part of an organization with an AWS IAM Identity Center instance that allows you to use Amazon Q. To use Amazon Q Developer agent for software development in Visual Studio Code, start by installing the Amazon Q extension. Find the latest version of the extension on the Amazon Q Developer page. The extension is also available for JetBrains, Eclipse (Preview), and Visual Studio IDEs. For a detailed list of supported IDEs and the features available in each, refer to the Amazon Q Developer documentation.

After authenticating, you can invoke the feature development agent by entering /dev in Amazon Q’s chat window.

Amazon Q Developer leverages an isolated sandbox environment to securely execute code generated by the Amazon Q Developer agent. This keeps the generated code running safely and in sync with the original codebase. Here’s a breakdown of how the process works:
- Initiating the Execution Environment: Upon receiving a prompt, the Amazon Q Developer agent initiates a sandbox instance or the customer specified docker container, which serves as a sandbox environment for code execution.
- Executing Commands Safely: The Amazon Q Developer agent safely executes a curated list of shell commands based on customer specifications in a Devfile. Devfiles model the configuration and dependencies of a development environment, enabling consistent environment reproduction and reducing manual setup effort. Developers can define custom commands within the Devfile to control actions in the sandbox, such as installing dependencies, running tests, applying database migrations, or executing build scripts, improving accuracy and efficiency.
- Feedback and Sync: After each command runs, changes to the code are tracked and the AI agent is provided with real-time feedback and enabling iterative improvements.
Use case example 1: Adding a test suite to an existing project
Let’s say you want to enhance the functionality of a React-based application, like the example react-solitaire from GitHub. As you add new features, it’s crucial to ensure that existing functionality remains intact and doesn’t break with each update. To achieve this, you aim to create a test suite for continuous testing and iteration of your code.
To illustrate this, we’ll clone the React project from GitHub and add a Devfile to define the environment and dependencies. The Devfile configures the sandbox to execute and test code changes safely, allowing updates to be made without affecting the working features.

Once the repository is cloned, place the Devfile in the root of the project folder. Then, open the Amazon Q IDE in Visual Studio Code and enter the /dev command to prompt the creation of a tailored test suite for the repository.

The Amazon Q Developer agent then begins analyzing your codebase, sharing real-time updates on the changes it’s making and files it’s working with. The agent starts by exploring the project structure, planning the necessary updates, and generating the test suite.

After a few steps, the agent has created the required test suites.

Then, the agent executes the tests, continuously monitoring for any failures. When an issue is detected, it doesn’t stop immediately—it actively improves the code based on feedback from the tests, repeating this process up to three times. If the issue remains unresolved after three iterations, the agent aborts the process. However, if the issue is fixed, it moves on to the next step. For instance, when the agent identified that Enzyme didn’t support React 18, it addressed the issue and re-ran the tests in the testing environment.
Once the issue was resolved, the agent moved on to the next step, displaying all the changes and files it has modified in the sandbox and asks if you want to accept the changes or provide feedback.

If you are satisfied with the output, you can accept the changes or you can provide feedback to the agent and request that it regenerates the code again.
Use case example 2: Re-run tests when a feature is updated
After successfully creating and executing the tests, the agent was prompted to add a new feature that displays the name of the game in the UI. The agent analyzed the repository, identified the files requiring updates, and determined the precise locations to implement the changes.

After applying the updates, the agent executes tests to validate the new feature, promoting seamless integration with the existing codebase and maintaining reliability throughout the development process.

Upon accepting the changes made by the agent, the index.html file is updated to include the text ‘Solitaire,’ integrating the new content smoothly into the existing project.

Conclusion
The launch of this new update in Amazon Q Developer marks a significant advancement in AI-driven development, transforming the Amazon Q Developer agent from a tool focused on code generation to a robust execution engine. By enabling developers to validate and test code changes in real-time, this enhancement can improve the accuracy and reliability of AI-generated files and fixes.
With flexible options to use AWS managed sandbox or bring custom environments, developers gain control to maximize the Amazon Q Developer agent’s potential. The new execution capability empowers teams to iterate faster, make informed adjustments, and leverage a secure, intelligent platform tailored to their needs.
You can try it out today by updating or installing your Amazon Q Developer extension on VS Code or JetBrains.
DeepSeek-R1 models now available on AWS
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/deepseek-r1-models-now-available-on-aws/
During this past AWS re:Invent, Amazon CEO Andy Jassy shared valuable lessons learned from Amazon’s own experience developing nearly 1,000 generative AI applications across the company. Drawing from this extensive scale of AI deployment, Jassy offered three key observations that have shaped Amazon’s approach to enterprise AI implementation.
First is that as you get to scale in generative AI applications, the cost of compute really matters. People are very hungry for better price performance. The second is actually quite difficult to build a really good generative AI application. The third is the diversity of the models being used when we gave our builders freedom to pick what they want to do. It doesn’t surprise us, because we keep learning the same lesson over and over and over again, which is that there is never going to be one tool to rule the world.

As Andy emphasized, a broad and deep range of models provided by Amazon empowers customers to choose the precise capabilities that best serve their unique needs. By closely monitoring both customer needs and technological advancements, AWS regularly expands our curated selection of models to include promising new models alongside established industry favorites. This ongoing expansion of high-performing and differentiated model offerings helps customers stay at the forefront of AI innovation.
This leads us to Chinese AI startup DeepSeek. DeepSeek launched DeepSeek-V3 on December 2024 and subsequently released DeepSeek-R1, DeepSeek-R1-Zero with 671 billion parameters, and DeepSeek-R1-Distill models ranging from 1.5–70 billion parameters on January 20, 2025. They added their vision-based Janus-Pro-7B model on January 27, 2025. The models are publicly available and are reportedly 90-95% more affordable and cost-effective than comparable models. Per Deepseek, their model stands out for its reasoning capabilities, achieved through innovative training techniques such as reinforcement learning.
Today, you can now deploy DeepSeek-R1 models in Amazon Bedrock and Amazon SageMaker AI. Amazon Bedrock is best for teams seeking to quickly integrate pre-trained foundation models through APIs. Amazon SageMaker AI is ideal for organizations that want advanced customization, training, and deployment, with access to the underlying infrastructure. Additionally, you can also use AWS Trainium and AWS Inferentia to deploy DeepSeek-R1-Distill models cost-effectively via Amazon Elastic Compute Cloud (Amazon EC2) or Amazon SageMaker AI.
With AWS, you can use DeepSeek-R1 models to build, experiment, and responsibly scale your generative AI ideas by using this powerful, cost-efficient model with minimal infrastructure investment. You can also confidently drive generative AI innovation by building on AWS services that are uniquely designed for security. We highly recommend integrating your deployments of the DeepSeek-R1 models with Amazon Bedrock Guardrails to add a layer of protection for your generative AI applications, which can be used by both Amazon Bedrock and Amazon SageMaker AI customers.
You can choose how to deploy DeepSeek-R1 models on AWS today in a few ways: 1/ Amazon Bedrock Marketplace for the DeepSeek-R1 model, 2/ Amazon SageMaker JumpStart for the DeepSeek-R1 model, 3/ Amazon Bedrock Custom Model Import for the DeepSeek-R1-Distill models, and 4/ Amazon EC2 Trn1 instances for the DeepSeek-R1-Distill models.
Let me walk you through the various paths for getting started with DeepSeek-R1 models on AWS. Whether you’re building your first AI application or scaling existing solutions, these methods provide flexible starting points based on your team’s expertise and requirements.
1. The DeepSeek-R1 model in Amazon Bedrock Marketplace
Amazon Bedrock Marketplace offers over 100 popular, emerging, and specialized FMs alongside the current selection of industry-leading models in Amazon Bedrock. You can easily discover models in a single catalog, subscribe to the model, and then deploy the model on managed endpoints.
To access the DeepSeek-R1 model in Amazon Bedrock Marketplace, go to the Amazon Bedrock console and select Model catalog under the Foundation models section. You can quickly find DeepSeek by searching or filtering by model providers.

After checking out the model detail page including the model’s capabilities, and implementation guidelines, you can directly deploy the model by providing an endpoint name, choosing the number of instances, and selecting an instance type.

You can also configure advanced options that let you customize the security and infrastructure settings for the DeepSeek-R1 model including VPC networking, service role permissions, and encryption settings. For production deployments, you should review these settings to align with your organization’s security and compliance requirements.
With Amazon Bedrock Guardrails, you can independently evaluate user inputs and model outputs. You can control the interaction between users and DeepSeek-R1 with your defined set of policies by filtering undesirable and harmful content in generative AI applications. The DeepSeek-R1 model in Amazon Bedrock Marketplace can only be used with Bedrock’s ApplyGuardrail API to evaluate user inputs and model responses for custom and third-party FMs available outside of Amazon Bedrock. To learn more, read Implement model-independent safety measures with Amazon Bedrock Guardrails.
Amazon Bedrock Guardrails can also be integrated with other Bedrock tools including Amazon Bedrock Agents and Amazon Bedrock Knowledge Bases to build safer and more secure generative AI applications aligned with responsible AI policies. To learn more, visit the AWS Responsible AI page.
Refer to this step-by-step guide on how to deploy the DeepSeek-R1 model in Amazon Bedrock Marketplace. To learn more, visit Deploy models in Amazon Bedrock Marketplace.
2. The DeepSeek-R1 model in Amazon SageMaker JumpStart
Amazon SageMaker JumpStart is a machine learning (ML) hub with FMs, built-in algorithms, and prebuilt ML solutions that you can deploy with just a few clicks. To deploy DeepSeek-R1 in SageMaker JumpStart, you can discover the DeepSeek-R1 model in SageMaker Unified Studio, SageMaker Studio, SageMaker AI console, or programmatically through the SageMaker Python SDK.
In the Amazon SageMaker AI console, open SageMaker Unified Studio or SageMaker Studio. In case of SageMaker Studio, choose JumpStart and search for “DeepSeek-R1” in the All public models page.

You can select the model and choose deploy to create an endpoint with default settings. When the endpoint comes InService, you can make inferences by sending requests to its endpoint.

You can derive model performance and ML operations controls with Amazon SageMaker AI features such as Amazon SageMaker Pipelines, Amazon SageMaker Debugger, or container logs. The model is deployed in an AWS secure environment and under your virtual private cloud (VPC) controls, helping to support data security.
As like Bedrock Marketpalce, you can use the ApplyGuardrail API in the SageMaker JumpStart to decouple safeguards for your generative AI applications from the DeepSeek-R1 model. You can now use guardrails without invoking FMs, which opens the door to more integration of standardized and thoroughly tested enterprise safeguards to your application flow regardless of the models used.
Refer to this step-by-step guide on how to deploy DeepSeek-R1 in Amazon SageMaker JumpStart. To learn more, visit Discover SageMaker JumpStart models in SageMaker Unified Studio or Deploy SageMaker JumpStart models in SageMaker Studio.
3. DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import
Amazon Bedrock Custom Model Import provides the ability to import and use your customized models alongside existing FMs through a single serverless, unified API without the need to manage underlying infrastructure. With Amazon Bedrock Custom Model Import, you can import DeepSeek-R1-Distill Llama models ranging from 1.5–70 billion parameters. As I highlighted in my blog post about Amazon Bedrock Model Distillation, the distillation process involves training smaller, more efficient models to mimic the behavior and reasoning patterns of the larger DeepSeek-R1 model with 671 billion parameters by using it as a teacher model.
After storing these publicly available models in an Amazon Simple Storage Service (Amazon S3) bucket or an Amazon SageMaker Model Registry, go to Imported models under Foundation models in the Amazon Bedrock console and import and deploy them in a fully managed and serverless environment through Amazon Bedrock. This serverless approach eliminates the need for infrastructure management while providing enterprise-grade security and scalability.

Refer to this step-by-step guide on how to deploy DeepSeek-R1 models using Amazon Bedrock Custom Model Import. To learn more, visit Import a customized model into Amazon Bedrock.
4. DeepSeek-R1-Distill models using AWS Trainium and AWS Inferentia
AWS Deep Learning AMIs (DLAMI) provides customized machine images that you can use for deep learning in a variety of Amazon EC2 instances, from a small CPU-only instance to the latest high-powered multi-GPU instances. You can deploy the DeepSeek-R1-Distill models on AWS Trainuim1 or AWS Inferentia2 instances to get the best price-performance.
To get started, go to Amazon EC2 console and launch a trn1.32xlarge EC2 instance with the Neuron Multi Framework DLAMI called Deep Learning AMI Neuron (Ubuntu 22.04).

Once you have connected to your launched ec2 instance, install vLLM, an open-source tool to serve Large Language Models (LLMs) and download the DeepSeek-R1-Distill model from Hugging Face. You can deploy the model using vLLM and invoke the model server.
To learn more, refer to this step-by-step guide on how to deploy DeepSeek-R1-Distill Llama models on AWS Inferentia and Trainium.
You can also visit the DeepSeek-R1-Distill-Llama-8B or deepseek-ai/DeepSeek-R1-Distill-Llama-70B model cards on Hugging Face. Choose Deploy and then Amazon SageMaker. From the AWS Inferentia and Trainium tab, copy the example code for deploy DeepSeek-R1-Distill Llama models.

Since the release of DeepSeek-R1, various guides of its deployment for Amazon EC2 and Amazon Elastic Kubernetes Service (Amazon EKS) have been posted. Here is some additional material for you to check out:
- Leveraging DeepSeek-R1 with CPU and GPU options on AWS by Daniel Wirjo
- Benefits of installing DeepSeek on an Amazon EC2 instance by Enrique Aguilar Martinez
- Deploying DeepSeek Llama models on Amazon EC2 inferentia instance by Irshad Chohan
- How to deploy and fine-tune DeepSeek models on AWS by Hugging Face
- Hosting DeepSeek-R1 on Amazon EKS Auto Mode by Tiago Reichert
Things to know
Here are a few important things to know.
- Pricing – For publicly available models like DeepSeek-R1, you are charged only the infrastructure price based on inference instance hours you select for Amazon Bedrock Markeplace, Amazon SageMaker JumpStart, and Amazon EC2. For the Bedrock Custom Model Import, you are only charged for model inference, based on the number of copies of your custom model is active, billed in 5-minute windows. To learn more, check out the Amazon Bedrock Pricing, Amazon SageMaker AI Pricing, and Amazon EC2 Pricing pages.
- Data security – You can use enterprise-grade security features in Amazon Bedrock and Amazon SageMaker to help you make your data and applications secure and private. This means your data is not shared with model providers, and is not used to improve the models. This applies to all models—proprietary and publicly available—like DeepSeek-R1 models on Amazon Bedrock and Amazon SageMaker. To learn more, visit Amazon Bedrock Security and Privacy and Security in Amazon SageMaker AI.
Now available
DeepSeek-R1 is generally available today in Amazon Bedrock Marketplace and Amazon SageMaker JumpStart. You can also use DeepSeek-R1-Distill models using Amazon Bedrock Custom Model Import and Amazon EC2 instances with AWS Trainum and Inferentia chips.
Give DeepSeek-R1 models a try today in the Amazon Bedrock console, Amazon SageMaker AI console, and Amazon EC2 console, and send feedback to AWS re:Post for Amazon Bedrock and AWS re:Post for SageMaker AI or through your usual AWS Support contacts.
— Channy
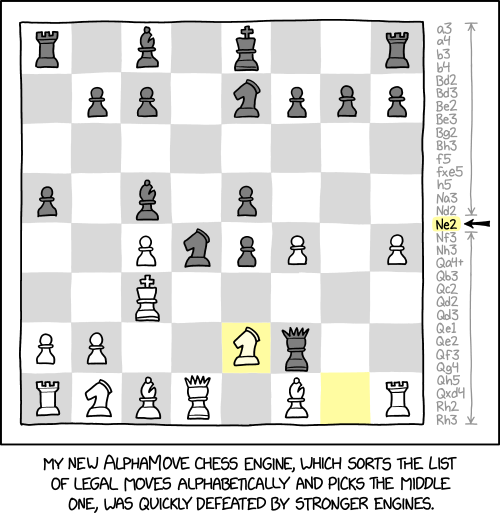
AlphaMove
Post Syndicated from xkcd.com original https://xkcd.com/3045/
Deadliest animal.
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=Hd6YntjlMYQ
[$] Resistance to Rust abstractions for DMA mapping
Post Syndicated from corbet original https://lwn.net/Articles/1006805/
While the path toward the ability to write device drivers in Rust has been
anything but smooth, steady progress has been made and that goal is close
to being achieved — for some types of drivers at least. Device drivers
need to be able to set up memory areas for direct memory access (DMA)
transfers, though; that means Rust drivers will need a set of
abstractions to interface with the kernel’s DMA-mapping subsystem. Those
abstractions have run into resistance that has the potential to block
progress on the Rust-for-Linux project as a whole.
Amazon Redshift enhances security by changing default behavior in 2025
Post Syndicated from Yanzhu Ji original https://aws.amazon.com/blogs/security/amazon-redshift-enhances-security-by-changing-default-behavior-in-2025/
Today, I’m thrilled to announce that Amazon Redshift, a widely used, fully managed, petabyte-scale data warehouse, is taking a significant step forward in strengthening the default security posture of our customers’ data warehouses. Some default security settings for newly created provisioned clusters, Amazon Redshift Serverless workgroups, and clusters restored from snapshots have changed. These changes include disabling public accessibility, enabling database encryption, and enforcing secure connections.
Amazon Redshift already supports encryption in transit and at rest. Database encryption is crucial because it helps safeguard sensitive data from unauthorized access. Furthermore, restricting public access can be advantageous because it limits the threat surface and helps prevent unauthorized access to the database. By confining the Amazon Redshift cluster within the customer’s virtual private cloud (VPC), the cluster is isolated from the public internet, which significantly reduces the possibility of unauthorized parties discovering and accessing the data warehouse.
Enforcing secure connections is another essential security measure. This enforces encryption of communication between the applications and the database, reducing the risk of eavesdropping and man-in-the-middle exploits, which helps protect the confidentiality and integrity of the data being transmitted.
By implementing additional security defaults for newly created provisioned clusters, Serverless workgroups, and clusters restored from snapshots, Amazon Redshift helps customers adhere to best practices in data security without requiring additional setup, reducing the risk of potential misconfigurations.
These new security enhancements include three key changes:
- Disabling public access by default – Public accessibility will be disabled by default for newly created or restored provisioned clusters. This means that the newly created clusters will be accessible only within your VPC and not accessible from the public internet. With this change, if you create a provisioned cluster from the AWS Management Console, then the cluster is created with public access disabled by default. Specifically, the
PubliclyAccessibleparameter will be set tofalseby default. This change will also be reflected in theCreateClusterandRestoreFromClusterSnapshotAPI operations and the corresponding console, AWS CLI, and AWS CloudFormation By default, connections to clusters will only be permitted from client applications within the same VPC. To access your data warehouse from applications in another VPC, you have to configure cross-VPC access.If you still need public access, you must explicitly override the default and set the
PubliclyAccessibleparameter totruewhen you run theCreateClusterorRestoreFromClusterSnapshotAPI operations. With a publicly accessible cluster, we recommend that you always use security groups or network access control lists (network ACLs) to restrict access. - Enabling encryption by default – With this change, the ability to create unencrypted clusters will no longer be available in the Amazon Redshift console. When you use the console, CLI, API, or CloudFormation to create a provisioned cluster without specifying an AWS Key Management Service (AWS KMS) key, the cluster will automatically be encrypted with an AWS-owned key. The AWS-owned key is managed by AWS.
This update might impact you if you are creating unencrypted clusters by using automated scripts or using data sharing with unencrypted clusters. If you regularly create new unencrypted consumer clusters and use them for data sharing, review your configurations to verify that the producer and consumer clusters are both encrypted to reduce the chance that you will experience disruptions in your data-sharing workloads.
- Enforcing secure connections by default – With this change, a new default parameter group named
default.redshift-2.0will be introduced for newly created or restored clusters, with therequire_sslparameter set totrueby default. New clusters created without a specified parameter group will automatically use thedefault.redshift-2.0parameter group. When you create a cluster through the console, the newdefault.redshift-2.0parameter group will be automatically selected. This change will also be reflected in theCreateClusterandRestoreFromClusterSnapshotAPI operations, as well as in the corresponding console, AWS CLI, and AWS CloudFormation operations.For customers who are using existing or custom parameter groups, the service will continue to honor the
require_sslvalue specified in your parameter group. However, we recommend that you update therequire_sslparameter totruein order to enhance the security of your connections. You continue to have the option to change therequire_sslvalue in your custom parameter groups as needed. You can follow the procedure in this topic in the Amazon Redshift Management Guide to configure security options for connections.
We recommend that all Amazon Redshift customers review their current configurations for this service and consider implementing the new security measures across their applications. These security enhancements could impact existing workflows that rely on public access, unencrypted clusters, or non-SSL connections. We recommend that you review and update your configurations, scripts, and tools to align with these new defaults.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
THE GREAT SERPENT MOUND: Prehistoric Effigy or Alien Construction?
Post Syndicated from Geographics original https://www.youtube.com/watch?v=3zhGduDRXOc
Voice – Chapter 9
Post Syndicated from Home Assistant original https://www.youtube.com/watch?v=k6VvzDSI8RU
Freedesktop looking for new home for its GitLab instance
Post Syndicated from jake original https://lwn.net/Articles/1007032/
Visitors to the freedesktop.org
GitLab instance are currently being greeted with a message noting that
the company who has been hosting it for free for nearly five years, Equinix, has
asked that it be moved (or start being paid for) by the end of April. The
issue
ticket opened by Benjamin Tissoires in order to track the planning of a move is clear that the project is grateful for
the gift:
“First, I’d like to thank Equinix Metal for the years of support they gave us. They were very kind and generous with us and even if it’s a shame we have to move out on a short notice, all things come to an end.
”
The current cost for the services, much of which is for 50TB of bandwidth data transfer
per month and a half-dozen beefy servers for running continuous-integration
(CI) jobs, comes to around $24,000 per month. Tissoires believes that the
project should start paying for service somewhere, in order to avoid
upheaval of this sort, sometimes on short or no notice. “I personally
” Various options are
think we better have fd.o pay for its own servers, and then have sponsors
chip in. This way, when a sponsor goes away, it’s technically much simpler
to just replace the money than change datacenter.
being discussed there, but any move is likely to disrupt normal services
for a week or more.
git submodules adoption flow
Post Syndicated from turnoff.us original http://turnoff.us/geek/git-submodules/

GNU C Library 2.41 released
Post Syndicated from corbet original https://lwn.net/Articles/1007024/
Version 2.41 of the GNU
C Library has been released. Changes include a number of test-suite
improvements, strict-error support in the DNS stub resolver, wrappers for
the the sched_setattr()
and sched_getattr() system calls,
Unicode 16.0.0 support,
improved C23 support,
support for extensible restartable
sequences,
Guarded Control Stack support on 64-bit Arm systems,
and more.
Run Deepseek Locally for Free!
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=pbCQnDDj-bo
Security updates for Thursday
Post Syndicated from jake original https://lwn.net/Articles/1006978/
Security updates have been issued by AlmaLinux (redis:7), Debian (bind9, chromium, flightgear, pam-u2f, and simgear), Red Hat (fence-agents, git-lfs, libsoup, python3.9, rsync, and traceroute), Slackware (bind), SUSE (apache2-mod_security2, corepack22, go1.24, hplip, ignition, iperf, kernel, kernel-devel-longterm, nginx, nodejs22, openvpn, owasp-modsecurity-crs, and shadow), and Ubuntu (bind9, jinja2, libxml2, linux-lowlatency-hwe-6.8, php7.0, tomcat6, and vlc).
Thunderbird moving to monthly updates in March
Post Syndicated from jzb original https://lwn.net/Articles/1006917/
The Thunderbird project has announced
that it is making its Release
channel the default download beginning with the 135.0 release in
March. This will move users to major monthly releases instead of the
annual major Extended Support Release (ESR) that is the current
default.
One of our goals for 2025 is to increase active installations on the
release channel to at least 20% of the total installations. At last
check, we had 29,543 active installations on the release channel,
compared to 20,918 on beta, and 5,941 on daily. The release channel
installations currently account for 0.27% of the 10,784,551 total
active installations tracked on stats.thunderbird.net.
Paying It Forward: Giving and Receiving Mentorship in Tech
Post Syndicated from Rapid7 original https://blog.rapid7.com/2025/01/30/paying-it-forward-giving-and-receiving-mentorship-in-tech/
I’ve never actually seen the 2000 romantic drama Pay It Forward, but the movie’s core idea has stayed with me since I first heard of it:
The best way to repay a favor or good deed is to do one for someone else. You ‘pay it forward,’ and ask that person to do likewise, creating an expanding web of positivity and goodwill.
Cliche as it may sound, it’s served me well over my career. I’ve had many roles over the past 20 years, starting as a junior engineer and progressing into management. My own mentors and coaches shaped my experiences along the way, contributing to that growth.
In return, I try to do the same for others.
Mentorship vs. coaching
I want to briefly look at ‘mentorship’ versus ‘coaching,’ as they are often conflated. There is certainly overlap, but the approach and impetus differs.
Mentorship involves dedicated guidance and support over time. The mentee drives the relationship, the ultimate goal, and the current focus. The mentor maps a path to the goal, and offers personalized knowledge and experience on a one-to-one basis.
Coaching is a more structured approach,primarily driven by the coach. It normally involves specific skill or knowledge training, and often isn’t personalized; it can be extended to groups with minimal change.
I believe that successful learning relationships operate on a spectrum between mentorship and coaching. Particularly in tech, where so-called ‘hard’ and ‘soft’ skills carry equal weight, the focus is a sliding scale over time.
For this article, I’ll focus on the ‘mentor’ and ‘mentee’ roles for simplicity.
Why do people seek mentorship?
Mentee-mentor relationships are inherently transactional – and that’s okay! The mentee has a goal to achieve, and wants help to get there. So what’s in it for both parties?
For mentees, it’s fairly obvious:
- Skills and experience growth
- Career advancement
- Increased profile and exposure
- Personalized individual guidance
The mentor – wanting to be diligent and accurate with their guidance – sees their own skills and knowledge reinforced. Communication and teaching skills grow. Their ability to elevate others is advantageous for their own career aspirations.
It’s okay to feel good about this – it’s a good thing.
Mentorship and career growth
As you climb the ladder in your career, you will find yourself gaining:
- The ability to handle increasing ambiguity, complexity, and scope
- Knowledge and experience you can share with others
Obviously you also have to deliver value, but I see that as a function of the above, plus institutional factors. Your increasing capacity to navigate complex or ambiguous environments, paired with an advanced set of skills, is what propels you from wide-eyed junior to seasoned veteran.
We’re all walking this path in some form. Juniors often need direction on what to do and how to do it. With more experience, there is less direction needed for ‘how’ and more focus on ‘what’ and ‘why.’ You start to own features and systems, and can guide others.
In higher roles, strategy comes to the forefront as you become more aware of business needs, customer requirements, and wider technical challenges. You’ve gone from ‘change this line of code’ to ‘increase this KPI by 20%’. Ambiguity, complexity, and scope all go up as a result..
In addition to changes in your deliverables, success also becomes measured by how well you can elevate others around you. At Rapid7, we look at leaders to be impact multipliers, meaning they have the capacity to drive impact not only in their own roles, but how they support those around them to be successful.
Additionally, you don’t have to wait to be in an official people leader role to have this kind of impact. Being a mentor and elevating others can happen regardless of where you are in your career journey.
Mentoring someone is an investment in the future. You chart a path to success, act as a role model, and in some ways shape the industry to come.
Getting started
Whether you’re looking to become a mentor – or seeking guidance as a mentee – the keys to getting started are relatively similar.
Seeking the right opportunities
- Take stock of where you have existing relationships to build off of, and ask for guidance while sharing what your goals are for entering into a mentorship relationship. – Let your colleagues and manager know that you’re available. Sharing your goals with your manager can help incorporate your mentor experience into your personal development plan, and they may even have recommendations on how to get started. Colleagues can be great mentors/mentees, and may also be able to help point you in the right direction to connect with someone. Seek opportunities on Slack, Discord, and other community channels. Going beyond your current employer can expose you to different practices and philosophies that exist within the same field or area of focus.
- Attend meetups and conferences to network and find opportunities. The goal of attending an event is often to gain knowledge and share best practices, so this is a great audience for you to find your mentor/mentee match.
Establishing guidelines and expectations
It’s important for both parties to agree on some foundational principles, which for me are:
- Mutual trust and respect
- Adequate investment of time, effort, and care
- Fluidity and flexibility
- Transparency, honesty, and accountability
Maintaining effective mentorships
Let’s look at some other factors to consider and watch for as the relationship evolves:
- Don’t over-prescribe structure or get bogged down in note-taking – keep it light and fluid to encourage maximum flexibility.
- There are no ‘stupid questions’ – don’t apologize as a mentee for asking!
- Leave ego at the door – embrace honest feedback and mutual respect at all times.
- Safety and trust are essential – but avoid getting too personal in ways that hinder your ability to be honest and open.
- Mentorship is a vital tool for managers – but transparency can suffer when the mentee is also a direct report. Peer relationships without these power structures can feel ‘safer’ and encourage better transparency.
Conclusion
When it comes to mentorship, my core point is this:
Helping people is good, and you can (and should) do it.
As a mentor, you have the opportunity to shape someone’s career and experience while galvanizing your own skills and future prospects. Start today, in whatever form you can.
As a mentee benefitting from guidance and support in pursuit of your goals, try not to forget to pay it forward. Find someone to guide and help on their journey, as you yourself have been.
Comic for 2025.01.31 – Jedi
Post Syndicated from Explosm.net original https://explosm.net/comics/jedi
New Cyanide and Happiness Comic
How Open Universities Australia modernized their data platform and significantly reduced their ETL costs with AWS Cloud Development Kit and AWS Step Functions
Post Syndicated from Michael Davies original https://aws.amazon.com/blogs/big-data/how-open-universities-australia-modernized-their-data-platform-and-significantly-reduced-their-etl-costs-with-aws-cloud-development-kit-and-aws-step-functions/
This is a guest post co-authored by Michael Davies from Open Universities Australia.
At Open Universities Australia (OUA), we empower students to explore a vast array of degrees from renowned Australian universities, all delivered through online learning. We offer students alternative pathways to achieve their educational aspirations, providing them with the flexibility and accessibility to reach their academic goals. Since our founding in 1993, we have supported over 500,000 students to achieve their goals by providing pathways to over 2,600 subjects at 25 universities across Australia.
As a not-for-profit organization, cost is a crucial consideration for OUA. While reviewing our contract for the third-party tool we had been using for our extract, transform, and load (ETL) pipelines, we realized that we could replicate much of the same functionality using Amazon Web Services (AWS) services such as AWS Glue, Amazon AppFlow, and AWS Step Functions. We also recognized that we could consolidate our source code (much of which was stored in the ETL tool itself) into a code repository that could be deployed using the AWS Cloud Development Kit (AWS CDK). By doing so, we had an opportunity to not only reduce costs but also to enhance the visibility and maintainability of our data pipelines.
In this post, we show you how we used AWS services to replace our existing third-party ETL tool, improving the team’s productivity and producing a significant reduction in our ETL operational costs.
Our approach
The migration initiative consisted of two main parts: building the new architecture and migrating data pipelines from the existing tool to the new architecture. Often, we would work on both in parallel, testing one component of the architecture while developing another at the same time.
From early in our migration journey, we began to define a few guiding principles that we would apply throughout the development process. These were:
- Simple and modular – Use simple, reusable design patterns with as few moving parts as possible. Structure the code base to prioritize ease of use for developers.
- Cost-effective – Use resources in an efficient, cost-effective way. Aim to minimize situations where resources are running idly while waiting for other processes to be completed.
- Business continuity – As much as possible, make use of existing code rather than reinventing the wheel. Roll out updates in stages to minimize potential disruption to existing business processes.
Architecture overview
The following Diagram 1 is the high-level architecture for the solution.

Diagram 1: Overall architecture of the solution, using AWS Step Functions, Amazon Redshift and Amazon S3
The following AWS services were used to shape our new ETL architecture:
- Amazon Redshift – A fully managed, petabyte-scale data warehouse service in the cloud. Amazon Redshift served as our central data repository, where we would store data, apply transformations, and make data available for use in analytics and business intelligence (BI). Note: The provisioned cluster itself was deployed separately from the ETL architecture and remained unchanged throughout the migration process.
- AWS Cloud Development Kit (AWS CDK) – The AWS Cloud Development Kit (AWS CDK) is an open-source software development framework for defining cloud infrastructure in code and provisioning it through AWS CloudFormation. Our infrastructure was defined as code using the AWS CDK. As a result, we simplified the way we defined the resources we wanted to deploy while using our preferred coding language for development.
- AWS Step Functions – With AWS Step Functions, you can create workflows, also called State machines, to build distributed applications, automate processes, orchestrate microservices, and create data and machine learning pipelines. AWS Step Functions can call over 200 AWS services including AWS Glue, AWS Lambda, and Amazon Redshift. We used the AWS Step Function state machines to define, orchestrate, and execute our data pipelines.
- Amazon EventBridge – We used Amazon EventBridge, the serverless event bus service, to define the event-based rules and schedules that would trigger our AWS Step Functions state machines.
- AWS Glue – A data integration service, AWS Glue consolidates major data integration capabilities into a single service. These include data discovery, modern ETL, cleansing, transforming, and centralized cataloging. It’s also serverless, which means there’s no infrastructure to manage. includes the ability to run Python scripts. We used it for executing long-running scripts, such as for ingesting data from an external API.
- AWS Lambda – AWS Lambda is a highly scalable, serverless compute service. We used it for executing simple scripts, such as for parsing a single text file.
- Amazon AppFlow – Amazon AppFlow enables simple integration with software as a service (SaaS) applications. We used it to define flows that would periodically load data from selected operational systems into our data warehouse.
- Amazon Simple Storage Service (Amazon S3) – An object storage service offering industry-leading scalability, data availability, security, and performance. Amazon S3 served as our staging area, where we would store raw data prior to loading it into other services such as Amazon Redshift. We also used it as a repository for storing code that could be retrieved and used by other services.
Where practical, we made use of the file structure of our code base for defining resources. We set up our AWS CDK to refer to the contents of a specific directory and define a resource (for example, an AWS Step Functions state machine or an AWS Glue job) for each file it found in that directory. We also made use of configuration files so we could customize the attributes of specific resources as required.
Details on specific patterns
In the above architecture Diagram 1, we showed multiple flows by which data could be ingested or unloaded from our Amazon Redshift data warehouse. In this section, we highlight four specific patterns in more detail which were utilized in the final solution.
Pattern 1: Data transformation, load, and unload
Several of our data pipelines included significant data transformation steps, which were primarily performed through SQL statements executed by Amazon Redshift. Others required ingestion or unloading of data from the data warehouse, which could be performed efficiently using COPY or UNLOAD statements executed by Amazon Redshift.
In keeping with our aim of using resources efficiently, we sought to avoid running these statements from within the context of an AWS Glue job or AWS Lambda function because these processes would remain idle while waiting for the SQL statement to be completed. Instead, we opted for an approach where SQL execution tasks would be orchestrated by an AWS Step Functions state machine, which would send the statements to Amazon Redshift and periodically check their progress before marking them as either successful or failed. The following Diagram 2 shows this workflow.

Diagram 2: Data transformation, load, and unload pattern using Amazon Lambda and Amazon Redshift within an AWS Step Function
Pattern 2: Data replication using AWS Glue
In cases where we needed to replicate data from a third-party source, we used AWS Glue to run a script that would query the relevant API, parse the response, and store the relevant data in Amazon S3. From here, we used Amazon Redshift to ingest the data using a COPY statement. The following Diagram 3 shows this workflow.

Diagram 3: Copying from external API to Redshift with AWS Glue
Note: Another option for this step would be to use Amazon Redshift auto-copy, but this wasn’t available at time of development.
Pattern 3: Data replication using Amazon AppFlow
For certain applications, we were able to use Amazon AppFlow flows in place of AWS Glue jobs. As a result, we could abstract some of the complexity of querying external APIs directly. We configured our Amazon AppFlow flows to store the output data in Amazon S3, then used an EventBridge rule based on an End Flow Run Report event (which is an event which is published when a flow run is complete) to trigger a load into Amazon Redshift using a COPY statement. The following Diagram 4 shows this workflow.
By using Amazon S3 as an intermediate data store, we gave ourselves greater control over how the data was processed when it was loaded into Amazon Redshift, when compared with loading the data directly to the data warehouse using Amazon AppFlow.

Diagram 4: Using Amazon AppFlow to integrate external data to Amazon S3 and copy to Amazon Redshift
Pattern 4: Reverse ETL
Although most of our workflows involve data being brought into the data warehouse from external sources, in some cases we needed the data to be exported to external systems instead. This way, we could run SQL queries with complex logic drawing on multiple data sources and use this logic to support operational requirements, such as identifying which groups of students should receive specific communications.
In this flow, shown in the following Diagram 5, we start by running an UNLOAD statement in Amazon Redshift to unload the relevant data to files in Amazon S3. From here, each file is processed by an AWS Lambda function, which performs any necessary transformations and sends the data to the external application through one or more API calls.

Diagram 5: Reverse ETL workflow, sending data back out to external data sources
Outcomes
The re-architecture and migration process took 5 months to complete, from the initial concept to the successful decommissioning of the previous third-party tool. Most of the architectural effort was completed by a single full-time employee, with others on the team primarily assisting with the migration of pipelines to the new architecture.
We achieved significant cost reductions, with final expenses on AWS native services representing only a small percentage of projected costs compared to continuing with the third-party ETL tool. Moving to a code-based approach also gave us greater visibility of our pipelines and made the process of maintaining them quicker and easier. Overall, the transition was seamless for our end users, who were able to view the same data and dashboards both during and after the migration, with minimal disruption along the way.
Conclusion
By using the scalability and cost-effectiveness of AWS services, we were able to optimize our data pipelines, reduce our operational costs, and improve our agility.
Pete Allen, an analytics engineer from Open Universities Australia, says, “Modernizing our data architecture with AWS has been transformative. Transitioning from an external platform to an in-house, code-based analytics stack has vastly improved our scalability, flexibility, and performance. With AWS, we can now process and analyze data with much faster turnaround, lower costs, and higher availability, enabling rapid development and deployment of data solutions, leading to deeper insights and better business decisions.”
Additional resources
- Orchestrate Amazon Redshift based ETL workflows with AWS Step Functions and AWS Glue
- Best practices for developing and deploying cloud infrastructure with the AWS CDK
- redshift-data-api-with-step-functions-sample
About the Authors
 Michael Davies is a Data Engineer at OUA. He has extensive experience within the education industry, with a particular focus on building robust and efficient data architecture and pipelines.
 Emma Arrigo is a Solutions Architect at AWS, focusing on education customers across Australia. She specializes in leveraging cloud technology and machine learning to address complex business challenges in the education sector. Emma’s passion for data extends beyond her professional life, as evidenced by her dog named Data.
Fake Reddit and WeTransfer Sites are Pushing Malware
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/01/fake-reddit-and-wetransfer-sites-are-pushing-malware.html
There are thousands of fake Reddit and WeTransfer webpages that are pushing malware. They exploit people who are using search engines to search sites like Reddit.
Unsuspecting victims clicking on the link are taken to a fake WeTransfer site that mimicks the interface of the popular file-sharing service. The ‘Download’ button leads to the Lumma Stealer payload hosted on “weighcobbweo[.]top.”
Boingboing post.
The War for Your Attention
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=MRDqQ8-HiwM