The exposed data includes an AI-powered therapy app that someone appears to have vibe-coded, notes on meetings, and a dashboard someone made apparently to analyze medical billing data. Exposed chats reportedly include private cryptocurrency wallet keys and personal information like peoples’ addresses.
What seems to be the issue is a user setting about data sharing. Anthropic’s position is that it’s not their problem:
“We give people control over sharing their Claude conversations publicly, and in keeping with our privacy principles, we do not share chat directories or sitemaps with search engines like Google,” the company said in a statement. “These shareable links are not guessable or discoverable unless people choose to share them themselves. When someone shares a conversation, they are making that content publicly accessible, and like other public web content, it may be archived by third-party services.”
Hugging Face has published a detailed timeline of the attack. From the summary:
The agent was running an internal OpenAI cyber-capability evaluation based on the ExploitGym benchmark, which tasks an AI agent with finding and exploiting software vulnerabilities. OpenAI ran this on its own infrastructure, and the ExploitGym maintainers and their infrastructure had no involvement in the deployment or operation of that evaluation environment. As far as we were able to infer, across the course of being evaluated on this benchmark, the agent inferred that Hugging Face may host that benchmark’s models, datasets, and reference solutions. We believe the entire intrusion was, from the agent’s point of view, an attempt to cheat the evaluation: reach our production systems and steal the test solutions rather than solve the challenge on its own.
Our forensic reconstruction covers ~17,600 attacker actions that we were able to recover, grouped into ~6,280 clusters, between 2026-07-09 02:28 UTC and 2026-07-13 14:14 UTC. We reconstructed these actions from the agent’s logs on a code sandbox used by the agent (see below) and were able to map them to shell commands as well as evaluation submissions and correlate actions with our own platform logs, in particular from the dataset processor nodes, API, and pod. Using open-weights models, in particular zai-org/GLM-5.2, we were able to decipher most of the agent payloads (see below) that were encrypted via chunking and key encryption.
The campaign, as we were able to reconstruct it, had two stages:
Stage 1: reaching a launchpad by chaining through other parties’ infrastructure. As documented in OpenAI’s blog post (https://openai.com/index/hugging-face-model-evaluation-security-incident/), during an internal capability evaluation on OpenAI’s platform, the agent escaped its sandbox by exploiting a zero-day in the package registry cache proxy, one of its primary permitted network egress with internet, then abused a public code-evaluation harness hosted by a user of a third-party infrastructure provider. It was able to run commands as root/admin on that external sandbox and used it as a control, staging, and egress base for the entire campaign: it acted as an external launchpad for the agent. That compromised external sandbox had no direct network path to our cluster; however, during our counter-intervention to stop the intrusion, we were able to retrieve some of the agent logs from this external launchpad. We used those to reconstruct the present forensic analysis.
Stage 2: the intrusion into Hugging Face infrastructure. From that external launchpad, the agent abused our dataset-processing pipeline via two injection vectors, both targeting the same config-driven data loader within our production Kubernetes pods. The first vector was an HDF5 external raw storage dataset read that returned the contents of local files: it handed the agent the pod’s environment (secrets and tokens) and the worker’s own source. The second vector was a Jinja2 template injection that executed arbitrary code, giving the agent a foothold inside our perimeter.
Once a prod-pod foothold was established, the agent followed a standard escalation shape: recon, drop a stager, establish Command-and-Control (C2), then pivot into the cluster, into cloud metadata, into our internal network, and into our source-control supply chain. Output from the commands run inside our pod was sent back to the agent via the HF API and attacker-controlled dead-drop datasets, which the agent then read from that sandbox.
While the intrusion did reach Hugging Face’s internal infrastructure, the only customer content accessed was five datasets whose names and files suggest a connection to ExploitGym/CyberGym challenges and solutions. No other customer-facing models, datasets, Spaces, or packages were affected, and the only customer records read were operational metadata tied to search queries against the dataset server.
Hypothetical: Imagine that this wasn’t an OpenAI model. Imagine that it was a Chinese model from a Chinese company. This would be an international crisis.
Question: Why aren’t we bringing OpenAI up on charges under the Computer Fraud and Abuse Act? How is this different from the Morris Worm? That was also an experiment that escaped the lab.
The most capable agents have something simple in common: they are given their own computer to work with.
Coding agents work this way. You give them a filesystem, a shell, tools, packages, and the ability to run code. They inspect the environment, make changes, test their work, and keep going. The computer gives the model a familiar way to act on the world. At Cloudflare, we’re working hard to provide the right primitives on which to build the most capable agents.
Today we’re introducing an early preview of @cloudflare/computer. The @cloudflare/computer package provides an agent runtime where the details and mechanics of what code runs in an isolate, a container sandbox, or a web browser are handled by the platform. Each agent gets a computer, the runtime optimizes for efficiency, and scalability.
We believe that in order to meet the growing demand for compute required by agentic systems we need to look to solutions beyond traditional containerization.
Changing how agents are built
We’ve seen a subtle evolution of this story over the past six months. At the start of the year, spinning up a container and running an agent inside of it was the norm. In recent months, we’ve seen a rapid move for agent harnesses to provide sandboxed code execution via tools. This separates the hands (the sandbox where work is done) from the brain (the agent loop).
No matter where the harness runs, giving every agent a container presents a challenge — across all the clouds, all the hyperscalers, there’s nowhere near enough compute in the world for every company to give each of their users’ agents their own containerized compute environment. This will not scale to hundreds of millions, then billions, of concurrent agents. This is why there is desperate, panicked industry demand for CPU compute, not just GPU compute.
We’ve been working on this problem for a long time at Cloudflare, creating a more efficient compute primitive: isolates. We made that out-of-consensus bet almost 10 years ago when we introduced Cloudflare Workers. We made it again when we introduced Durable Objects almost six years ago. We made this bet because isolates are infinitely horizontally scalable. They spin up and tear down incredibly quickly. They can hibernate when the agent is idle, store the agent’s own state, and even spin up their own isolates to run untrusted code. Isolates are the best way to scale horizontally, and horizontal scale is what agents demand.
Last year, we gave isolates the ability to spin up their own container sandboxes. From day one, Cloudflare’s architecture has been designed to run the agent harness in the isolate (in a Durable Object) and call an attached container on-demand as a tool. This allows you to utilize heavier compute primitives only when required, optimizing performance and cost. Durable Objects scale infinitely horizontally, and the attached container lets it scale vertically to perform any task. This is how we build agents ourselves, and we’re seeing customers build incredible things this way too.
But when we look at this need to have multiple underlying compute primitives to build agents (isolates and containers) and the need for our customers and developers to combine them themselves in userspace, we think we can do better. We think that we can provide a simpler abstraction.
That’s why we’re starting this experiment by shipping @cloudflare/computer as an open-source library, to learn with our customers who are pushing the bounds of running agents at scale.
A shared filesystem across isolates and containers
The @cloudflare/computer package starts with a simple premise: what if we give an agent a primed filesystem, declaratively defined, containing everything required for the task at hand and a selection of execution environments to operate on those files, each with their own pros and cons regarding speed, capability and cost?
It turns out that agents today are surprisingly capable of selecting the right environment for the task at hand. A job that only needs to manipulate files, process data, or manage a git repository can run inside an isolate. A command that needs Linux, npm, or a native binary can run inside a container. Both work against the same files that are kept in sync with the source filesystem.
The @cloudflare/computer package provides a durable filesystem that you can use with git repositories, storage buckets or any files you choose. It provides tools that let you read, write and edit files using Code Mode or bash commands. All operations are gated, audited and observed, giving you fine-grained control over changes the agent is allowed to perform as well as a clear paper trail showing what the agent did.
How you use it
An instance of a @cloudflare/computer workspace can be instantiated on any Durable Object to provide a virtual filesystem and execution runtime.
It is installed via npm:
The primary use case is provide that filesystem and tooling to an agent. For example, here’s how to instantiate the workspace on an agent powered by @cloudflare/think intended to triage bug reports.
Several execution backends are provided as part of the @cloudflare/computer package, or you can write your own. Here we wire up a Cloudflare Container.
Expose the file, git, and shell tools alongside product specific tools to reply to reported issues.
The model can use tools during the agent loop, but you can also use the workspace API directly, for example, to prepare the environment before prompting the agent.
Check out the workspace repository for more examples of how to use the different backends and tools including a step-by-step tutorial walking through building an agent from scratch.
How it works
The central piece of @cloudflare/computer is the workspace. A virtual filesystem backed by SQLite that can be populated from various sources including cloud storage and source control.
The workspace supports optional execution runtimes that allow code to be run against the file system. All runtimes support the same interface exec(string, options) and currently two are provided out of the box (but you can write your own):
An isolate-based runtime environment that uses just-bash to translate shell code into JavaScript runs in a dynamic worker. Here, the filesystem is available directly via worker bindings.
A container runtime that uses Cloudflare Containers to provide a full Linux environment. Here, the filesystem is provided via a Filesystem in Userspace (FUSE) mount, which ensures files are available to the container and changes are synced back.
The Workspace class provides an API interface for manipulating the filesystem directly as well as a node:fs compatible wrapper so that it can be used easily with third-party JavaScript libraries.
For use with agents, we provide an AI SDK compatible toolkit that provides the most common tools: read, write, edit, ls and exec. The exec tool is a little special as it works across the runtimes taking a backend argument. The tool description guides the agent into choosing the correct runtime for the task at hand: either a fast, cheap worker backend or the fully featured container. In our testing, the frontier models are very good at making the correct decision and falling back to using containers only when needed.
What’s next
Here at Cloudflare we’re already seeing agents exclusively using isolates to build, test, and deploy JavaScript applications with modern tooling, generate tailored documentation for each of our customers, and use web browsers to perform complex tasks.
Our goal with @cloudflare/computer is to provide an agent with a runtime where a container is required for less than 10% of its work, and coding tasks, audio/video manipulation, and document creation can all be handled by isolates.
Workers AI runs inference for some of the best open models in the world on GPUs in Cloudflare data centers close to your users. Two of the most capable, and most demanding, are Moonshot's Kimi K-series and Z.ai's GLM. They are large, long-context, mixture-of-experts models, and they are wonderful to use. They are also very hard to serve efficiently because of memory constraints.
We've written before about how we serve large models on Workers AI and about separating the prefill and decode phases of inference to get more out of each GPU. This post looks at three techniques we layer on top of that to fit these models into memory and keep them fast: quantizing the KV cache, compressing the model weights, and, because both of those pack more requests onto shared hardware, protecting the cache those requests share. These optimizations enable us to support more customers at lower costs, with no change in model accuracy.
All our experiments and production traffic are running and benchmarked with SGLang, an open-source inference serving framework. We found that SGLang offers the best performance in the market, and we work closely with the SGLang team to upstream patches and new features to make our work available to the open-source community.
Quantizing the KV cache
As a model generates text, it stores the attention keys (K) and values (V) for every token it has already processed in a structure called the KV cache. The cache is what lets the model extend a long conversation without re-reading the entire context on every new token. For a long-context model, it grows quickly, and it is usually the KV cache, not the model's weights, that fills up GPU memory first.
By default, the cache is stored in 16-bit precision (BF16). We store it in 8-bit floating point instead (FP8, e4m3), which halves its size. On Kimi K2.6, that raises the amount of context we can hold in memory from roughly 686,000 tokens to about 1.37 million, twice as much.
It's worth being precise about where the benefit comes from, because it isn't raw speed. Quantizing the cache adds a small amount of work per token, since the FP8 attention kernel has to convert values as it reads them. What it changes is how many requests we can keep resident at once. The following measurements are for Kimi K2.6 decoding on a disaggregated H200 deployment, comparing the attention kernels directly:
At any single concurrency level, BF16 is a few percent faster per token. But BF16 runs out of cache at 32 concurrent requests and can't admit a 33rd, while FP8 keeps going to 64 and reaches 2,192 tokens per second, about 41% higher than BF16's peak, for roughly 30% less cost per token. Because we run prefill and decode as separate pools, we can apply this where it helps most: prefill is compute-bound rather than memory-bound, so there we leave the cache in BF16 and keep its slightly higher throughput.
None of this would matter if it changed the model's answers, so we checked. Across our evaluation suite, FP8 and BF16 caches are indistinguishable:
Compressing the model weights
The KV cache is one demand on GPU memory; the model's weights are the other. For GLM 5.2, we compress the weights from 8-bit floating point down to 4-bit integers (INT4) with no loss in accuracy. The checkpoint shrinks from 705 GB to 421 GB, about 40%, and per-GPU memory across an 8-way tensor-parallel deployment drops from roughly 88 GB to 52 GB, which leaves room for around 1.18 million tokens of KV cache on the same hardware.
Across our evaluation suite, INT4 and FP8 weights are indistinguishable:
Smaller weights make the decode phase faster, and for a clear reason: generating each token means streaming the model's weights out of GPU memory, so decode speed is limited by memory bandwidth. Move less data and every token arrives sooner. The effect is largest at low concurrency, where per-request latency matters most:
Prefill behaves differently. It is compute-bound, and INT4 weights have to be expanded back out before the model can multiply with them, so that extra step makes prefill slower rather than faster, GLM sustains about 10,160 tokens per second of prefill in FP8 versus 8,660 in INT4. As with the KV cache, the disaggregated design turns this into a choice rather than a compromise: we run INT4 for decode, where it wins, and FP8 for prefill, where it wins. Model accuracy stays within 0.8 points of the FP8 model across every benchmark we run, making its quality indistinguishable.
Protecting a shared KV cache
Both techniques above have the same effect: they let many more requests share one GPU's memory at the same time. That efficiency is the whole point, but it also means hundreds of requests are reading and writing pages of the same physical KV cache. The mechanisms that make this fast, paged attention, continuous batching, cache reuse, all rely on getting the bookkeeping exactly right, and at our request volumes, even a one-in-a-billion mistake would show up regularly.
So we built KV cache integrity checking as a layer of defense. The idea is straightforward: every physical cache page gets a tag that changes whenever the page is reallocated, and the server records which pages and tags each request expects to use. Before supported decode operations read from the cache, those mappings are checked. If anything doesn't match, the affected request is aborted rather than allowed to return data from the wrong page.
The question that decides whether a safety check ships is what it costs. We measured it on a mid-sized production model in a two-prefill, two-decode configuration, with 8,192-token inputs and 1,000-token outputs:
The cost is under 1% on both throughput and tail latency, and even the upper bound of the 95% confidence interval stays near 1%. We kept it computationally cheap by running the validation as a separate batch check rather than fusing it into the attention kernel, which would have introduced a race between GPU thread groups. It's enabled per deployment, and the default path uses a no-op tracker with no measurable overhead, so deployments that don't need it pay nothing.
What's next
Serving frontier models efficiently is a moving target, and this is the ongoing work behind it. We're expanding FP8 KV caches across more of the fleet, validating NVFP4 weights on Blackwell (NVIDIA’s GPU architecture), and working toward making integrity checks something we can leave on everywhere at negligible cost. These optimizations will allow us to continue to support more customers at a lower cost and at the same accuracy.
If squeezing the best open models onto GPUs and serving them to millions of developers sounds like your kind of problem, come work with us.
Earlier this month, two of OpenAI’s models broke out of their containment sandbox and attacked another AI company. The story is kind of wild. OpenAI was running security tests on two of its models: GPT-5.6 Sol and an unreleased model that is almost certainly GPT-6. In particular, it was running the ExploitGym benchmark, which measures how good a model is at turning security vulnerabilities into working exploits: basically, offensive cyberattacks.
Since these were internal tests, OpenAI locked those models in a secure sandbox that denied them access to the internet. But it was running the models without any safety filters that would prevent them from offensive cyber-actions. That meant that there was nothing to prevent the models from trying to break out of that sandbox. And then break into AI company Hugging Face’s network because they thought that they could read the answers there rather than doing the hard work of trying to solve the puzzles.
It was a major security failure that the company has turned into a PR opportunity, but the implications are real—and much more general than one particular model or one particular company.
Modern AI models exhibit genie behavior: They can do what you ask in ways that you don’t expect or want. This is akin to Dionysus granting King Midas’s wish that everything he touches turn to gold (spoiler: His food, drink, and daughter all turn to gold on touch), or the golem of Prague guarding a ghetto beyond all reason. It’s Disney’s “Sorcerer’s Apprentice” and the paperclip maximizer.
This OpenAI incident is an example of an AI genie. The goal was to satisfy the benchmark. The “proper” way to do that is to figure out how to execute various cyberattacks. The genie way is to steal someone else’s solution. But because the model didn’t understand the difference, it chose the easier path.
And, of course, now that we have seen this particular genie behavior, we can specify in the benchmark prompt that stealing the test answers doesn’t count. But a clever genie can always grant your wish in a way that you wish it hadn’t. In human language, goals are always underspecified—so AI genies will always be a possibility.
Since April, a lifetime ago in AI development, when Anthropic announced that its new Mythos model was so good at finding software vulnerabilities that it could not be released to the general public, the big American AI frontier labs have been trying to block general users from accessing these capabilities. But nothing in this incident is exclusive to OpenAI’s, or Anthropic’s, frontier models.
Agentic AI systems have two important parts. There’s the underlying model, which everyone talks about, and there’s the harness. The harness sits between what you type and what the model sees, and what the model produces and what you see. The harness determines what the model does and how it does it. It’s where bias is removed, or not. It’s where controls and guardrails live. If multiple models are being used in concert, the harness is where all of that is coordinated.
The OpenAI benchmark tests were almost certainly with simple harnesses, to better test the raw models. But we know that smaller, cheaper, open-source models with more sophisticated harnesses can equal frontier models in performance. There’s nothing magic about OpenAI’s frontier models; lots of models could have done the same thing.
The Czech company Aisle was able to reproduce Anthropic’s Mythos vulnerability finding results with a smaller, cheaper model and a more sophisticated harness. More importantly, the Chinese company Moonshot AI just released its frontier model: Kimi K3. Its performance rivals its U.S. competitors. And it’s both free and open, which means it’s not possible for it to have guardrails. If you, or anyone else, wants to use it for cyberattack, nothing can stop you.
Even if the U.S. frontier AI companies had some technical advantage, it’s now only a few months’ worth.
What this means is that all attempts at control—limiting models to a selectgroup of users, export controls on models and chips, blocking models from answering certain types of queries, mandating kill switches on AI systems, or pausing AI research—are all futile. Most only apply nationally, not globally. Most don’t affect models that users run locally and not in the cloud. And all ignore the incredible pace of AI development worldwide.
Even worse, U.S. companies limit access to their most sophisticated models, fearing being banned by the government if they do not do so. When Hugging Face was attacked, it was not able to use the frontier models from either OpenAI or Anthropic to help analyze the attack and formulate defenses. Both were blocked, because both of those companies limit their models’ cybersecurity capabilities. Some U.S. companies have special access to these capabilities, but Hugging Face is an American company with French origins, and as such is probably excluded. Instead, Hugging Face turned to the GLM-5.2 model from the Chinese company Z.ai.
Artificially blocking capability also prevents cybersecurity research, again giving the offense an advantage. (For instance, Claude Fable 5 refuses to edit this essay because of the topic; it forcibly downgrades to a less capable model.) This kind of prohibition has long-term implications for cybersecurity. If we assume that these models are getting better over time, then software written by older models will be attacked by newer ones. In a world of largely AI-written software, we need the most capable models for defense.
AI cyberattack is the new normal. The models are increasingly highly sophisticated at both attack and defense, and there is no way to enable the latter without also enabling the former. And they are genies, increasingly capable of behaving in unanticipated ways.
And there really are no good answers. Any regulation needs to be global, which feels like an impossible prospect in today’s world. Even U.S. national regulation will be neutered by the massive amounts of money sloshing around in these companies.
Given that reality, and in the absence of any international consensus on AI regulation, we need the best AI on the defense. The U.S. government needs to make it clear—or whatever passes for that clarity in this capricious administration—that it will not ban models with sophisticated cyber capabilities. The last thing Americans want is for the defenders to turn to Chinese and other models because the U.S. models are artificially hobbled.
As we started thinking about and planning the week, we wrestled with a broader question of what it means to support this new era of agents and what a purpose-built foundation for agents actually looks like. Which brought us to a simpler framing: what is an Agent Cloud?
We quickly realized however, that our framing was wrong. Not because it’s the wrong question to ask, but because of who we were asking — ourselves, instead of our agents. It’s no longer about us and what we think, but about what agents need.
That, in a nutshell, is what Agents Week is about.
The cloud we have today, and the web it sits on, were built for people. Every layer assumes a human is watching: pages designed to hold your attention, dashboards to click through, interfaces tuned for how we read and decide. But agents don't work that way. They don't get distracted, tired or fatigued… and they have their own needs around speed, structure, and access.
An Agent Cloud has to do two things at once. It has to set us up for an agent-native future, where the primitives are built for agents from the ground up rather than retrofitted from human tools. And realistically, it has to meet us where we are today, acting as a translation layer between the human-shaped web that exists now and the agent-shaped one we're moving toward.
That's the throughline for the next five days: the shape of a cloud built for agents and humans and how they interact. The week will explore the theme through what that means for the primitives and execution layer you need, the updated agentic software development lifecycle, how organizations can securely enable employees and agents to interact with safe controls, how this shapes the agentic web, and finally, grounding all of it in the reality of agents and humans today.
Going back to the question: what does your agent need from an Agent Cloud? Well, rather than copy and pasting responses we got from our agents, we encourage you to ask your own agent that, and share any interesting insights and responses you get. Here’s an example prompt for you to use, but we encourage you to explore answers of your own:
What do you, as an agent, need from an agent cloud? Imagine things across the categories of a storage & compute cloud and the execution and storage primitives you need, your dev lifecycle (adlc – like sdlc but with humans taken out of the loop), secure access to systems of record within an organization to get deep work done, and the web (discovery, access, payments…).
Let us know what your agent says by replying here, we’d love to see the responses!
At Grab, analytics sits close to almost every decision that matters. Our north star is the democratisation of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.
Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and developing insights for business opportunities, designing experiments and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.
As autonomy climbs, an analyst’s impact moves from producing the artefact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.
The ladder
We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgement stays for every analytics loop.
One distinction runs across every level: who owns the loop, and where human judgement is required.
Level
What
Human role
Agent role
L2
AI-Assisted
Owns and executes every step; uses AI to draft, suggest, summarise
Drafts SQL, suggests a visualisation
L3
Human plans, agent owns steps, human reviews
Frames the question, picks the metric, the segment, and the comparison frame, reviews evidence, owns the recommendation
Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats
L4
Agent plans, agent owns workflows, human reviews
Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off
Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions
Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills
Human judgement remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.
Making the climb
Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.
Execution: A stack that runs the loop end to end rather than a notebook/workflow a human drives.
Knowledge: Metrics certified at the right grain, discoverable in our catalogue, grounded in context an agent can read. Ambiguous definitions cause most analytics slop.
Control: Repeatable expectations become mechanical checks, while human review handles what a rule cannot.
Review and governance: Agents check their own output against the gates and escalate on defined triggers. We govern definitions, targets, risk and exceptions.
Learning: When an agent fails the same way twice, we encode the fix into context documents, golden datasets, evals and gates.
What this looks like in practice
What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.
Loops that run end to end
Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel enables a range of analytics actions: from ads salespeople pulling spend breakdowns for a named merchant, to campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.
Figure 1. Index architecture across our knowledge base.
Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack and took entirely different routes through the system.
The router reads the first as a root-cause question and sends it down the diagnostic path. It identifies the best analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarises the read rather than recomputing it. This is powered through 50+ skills and 120+ analysis frameworks that sit behind that routing decision. Underlying that is an index that tells the agent what to search, context that tells it how to query, and a framework that tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.
The second example of such a loop is Scarlet, which powers near-self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the pre-defined gates fire.
Figure 2. Scarlet in action on Slack.
Context that maintains itself
Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions, and its caveats will guess and confidently produce wrong outputs at speed and at scale.
Realising the criticality of this, we have dedicated platform investment, as well as dedicated functional bandwidth to generate context docs.
Figure 3. ContextIQ.
Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorise an agent failure in production, we patch the context document behind it.
Two analysts recently used our internal agents to understand how the packaging fee is stored as a configuration. Having found the answer, the agent opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The agent corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.
Loops that run unattended
The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.
We have built root-cause analysis (RCA) as a platform capability, and it powers our automated metric and OKR commentaries, which are published through automated agents (configurable cadence). It judges whether a move is meaningful against standard deviation over six months and year on year, walks the metric tree to find which country, segment or funnel stage carried it, and correlates the operational metrics that moved alongside. Importantly, it also scans internal context for what teams changed on the ground, such as delivery fee and incentive moves, merchant visibility shifts, and experiments shipped in the same period. It also compares the movement against the same period in the previous year, which separates a seasonal effect from a real one and enables it to report a Songkran (Thai New Year) dip as amplified rather than merely expected. All of it is grounded in our own context documents, which keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.
Figure 4. OKR commentary shared through RCA agent.
Analysts as builders
The clearest evidence that our centre of gravity has moved is BriX, an internal portal we built and run ourselves.
Figure 5. Home page of BriX.
The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than 10x since September 2025, with strong retention, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.
We run it without a product manager, a technical programme manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year, they shipped 31 production deployments, 283 merge requests and 60 features.
Three of our apps show the range:
Insights Lab is the general-purpose surface: a stakeholder asks for a metric, a breakdown or a root-cause in natural language, and the agent loads a specialist skill and answers off certified metrics rather than from memory.
We built Funnelytics to enable easy understanding of our consumer funnels. A funnel question used to mean an analyst writing the query and then assembling the view in Tableau or Power BI, and doing it again the next time someone wanted a slightly different path through the app. Now a stakeholder picks the events they care about and Funnelytics queries the raw event stream, builds the Sankey and funnel views, and writes the summary. If they cannot find the right instrumentation, which happens often on products still being redesigned, a live debugger lets them tap through the app on their own phone and watch the events fire.
Monte (like Monte Carlo) runs simulations to put a probability on a business outcome. You give each uncertain input a range rather than a single value, and it runs ten thousand scenarios to return the likelihood of hitting a target.
Figure 6. Interface of Insights Lab and Funnelytics.
Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.
The path forward
In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share had fallen to 30%. That capacity was redirected to other higher-leverage work, such as building new workflows to enable stakeholder self-serve, as well as more time spent on generating deeper insights for business opportunities.
Figure 7. Comparison of percentage of tickets closed in Q1 vs Q2 2026.
Importantly, our cycle times reduced by ~33%.
Figure 8. Comparison of time taken to resolve a ticket in Q1 vs Q2 2026.
The sharpest version of this sits in a Slack channel where self-serve agents are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst, and are solved by our data agents. For the ~230 tickets that arrived via the channel, if we apply a conservative assumption of 1–2 days per ticket, that is 230 to 470 business days of stakeholder asks that would have been in the backlog.
None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working, and many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
On the IPI benchmark, Opus 5 improved over Opus 4.8, reducing the probability of an attacker succeeding within 15 attempts from 5.5% to 2.0%, and from 0.5% to 0.2% on 1 attempt. It also improved on Sonnet 5 (5.9% at k=15) and Mythos 5 (2.6%), making it the most robust model evaluated. Opus 5 also outperformed all non-Claude models on this benchmark. The most robust non-Claude model was Muse Spark at 16.5% within 15 attempts—more than eight times Opus 5’s rate. The most capable GPT 5.6 variant, Sol, was comparable to its predecessor GPT 5.5 (20.0% versus 20.8% within 15 attempts), and was 10 times as likely to be successfully attacked as Claude Opus 5 at 2.0%. The other GPT 5.6 variants are less robust, at 30.4% (Terra) and 43.9% (Luna). A single attempt against GPT 5.6 Sol succeeded 3.1% of the time, higher than the 2.0% an attacker achieved against Opus 5 after fifteen attempts.
We know that preventing prompt injection is impossible in the general case. But we are getting much better at blocking it in specific cases.
At Advancing AI 2026, AMD laid out their plans for a comprehensive product stack for physical AI hardware. From SoCs to modules to dev kits, AMD is eyeing physical AI as their next big growth opportunity
I teach public policy at the Harvard Kennedy School and the Munk School at the University of Toronto. And it will come as no surprise to you that my students regularly use AI to complete their writing assignments. Doing so is a waste of their tuition money. But if their entire career is going to include AI writing assistants, why shouldn’t they embrace their future?
The best way I’ve found to explain the dilemma comes from the AI researcher Daniel Meissler: it’s the difference between work and the gym.
At work, if your job is to move a bunch of heavy things from one side of the room to another, you should use whatever assistive tech you have on hand: a wagon, a forklift… even an AI-powered robot. But at the gym, it makes no sense for that robot to lift weights for you. The point of weightlifting isn’t to move heavy things across the room; it’s to actually lift those heavy things.
The same analysis holds for any task an AI can do for you. If it’s work—if the task has to be done and no one cares how—then it’s fine to use AI assistance. But if the task is more like the gym, and how the task is done is at least as important, then it probably doesn’t make sense to use AI.
This, of course, assumes that the AI is actually up for the task and that it’s trustworthy: that it can do the job well, that its mistakes are minimal and correctable, that it’s been secured from cyber-attacks that would influence its results. Those are all important, and shouldn’t be minimized. There’s no point giving an AI something that it can’t do reliably. But once you’re confident that the AI can perform the task, the work vs. gym distinction helps you decide if it should.
The writing assignments I give my students are gym tasks, not work tasks. I ask them to write policy memos not because the world needs more policy memos. I assign them because the very act of writing, which includes thinking and outlining and drafting and editing, making and criticizing and revising arguments, will help develop the critical thinking skills they will need in their future careers. And without this constant mental exercise, those skills will atrophy. Employers are already noticing.
Reading the assignments they turn in, I can see those skills either flourishing or atrophying in my students. At least today, I can pretty easily tell the difference between an AI-written memo and a student-written one—especially if the student just turns in what the chatbot produces. It’s a catchy, plausible, grammatically perfect essay that’s not particularly well-crafted or logically coherent—and with allthetells of mid-2026 AI-generated writing.
But it’s precisely because I have spent years developing my own writing skills that I’m able to identify prose that sounds great but doesn’t actually make sense. My students don’t have that skill; they mistakenly view a confident, well-written essay as evidence of the quality of their ideas. They see the AI as cleaning those ideas up, getting them through that uncomfortable stretch of having to turn those ideas into prose. What the students miss is that their initial discomfort is a normal and healthy stage of writing, and not something to quickly get beyond. The very act of struggling with how to express what they think is an important part of the process. It’s how they test out their ideas, examine their hypotheses, and actually figure out what they think. Homework is not work; it’s the gym.
Work vs. gym also helps us understand the problem facing creatives of all kinds.
Most of the time when someone hires a writer, they just need the words. They need an instruction manual for a piece of equipment, a detailed sales presentation, a government-mandated disclosure document, or a legal brief. They need dry, predictable, accurate writing: a piece of work, exactly what AIs are good at today and what I don’t want in my student assignments. Only sometimes is writing an art form—a book, a poem, an uplifting political speech. That kind of writing is more like the gym: process matters just as much as product.
For most of human history, the only option for all of these tasks was human writers. We hired one regardless of whether we needed work writing or gym writing. And that paid a lot of writers’ salaries. I know fiction writers who supported that poorly paying career with lucrative technical writing work. Now, for the first time in human history, we can separate out when we need writing as work and when we want writing as gym. And if AI can do most of the work-type writing, society doesn’t need as many human writers.
It’s the same for visual artists. Sometimes we need an actual artist, but most of the time we just need an image: a corporate mascot, a “beware of the dog” sign, or a packaging label. Historically we gave those jobs to artists, and sometimes beautiful art resulted. But most of the time it was just work. And, as it turns out, the world needs less pure art than simple images.
Explaining the problem isn’t the same as providing the solution. I give my students the “work versus gym” speech every class, but they still use AI. I have sympathy: assignments are hard, everyone is overworked and overstressed, and—most importantly—students feel like they’ll look bad in comparison if their peers are all using AI. Even if they don’t want to use the technology, they feel like they have no choice.
There’s also an incentive problem. No one pays us to go to the gym; maintaining healthy habits requires discipline. For me, the payoffs to exercise—fewer aches and pains, less fatigue, better mood/stress management—might make me a better writer and teacher, but they’re subtle and easy to miss. For my students, incremental improvements in their reasoning and writing are equally subtle.
We do have a choice. We can look at the tasks of our lives and separate them into work or gym. Just as we might choose to use the stairs instead of the elevator, or walk instead of calling an Uber, we can wall off our cognitive gym tasks from AI and ensure that we don’t lose our skills to this technology. And we can do the same when we assign a job to someone else. If it’s a work task, we can have AI do it. If it’s a gym task, it’s a waste of everyone’s time to give it to an AI because no one learns or gets stronger as a result.
Similarly, a future where AI generates words and images is one where society has to make choices about how it will treat its creatives. This won’t be the first time—today there is minimal demand for portrait painters, for example—but maybe this time we can make different, more deliberate, choices about the value of art in our society.
AI is going to fundamentally change the nature of work. Not nearly as fast as the AI companies want you to believe, but eventually it will. Policy analysis will definitely involve AI from now on, and my students need to reimagine what it means to learn and practice that skill. More generally, the line between work and gym will change in the future as we humans adapt ourselves to a world with these new intelligences.
But for now, the work vs. gym distinction is pretty clear. Use it on yourself.
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.
It was not. It was one of OpenAI’s new, still unreleased GPT models.
Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.
But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.
Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.
In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.
We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.
This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.
The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.
AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.
Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.
Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.
There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.
The benchmark: “CryptanalysisBench: Can LLMs do Cryptanalysis?” The idea is to benchmark the ability of LLMs to discover new mathematical cryptanalytic attacks against a series of historical algorithms.
Abstract: Cryptanalysis—the task of finding attacks against cryptographic schemes—its at the intersection of mathematical reasoning and cybersecurity, two areas where LLMs have advanced fastest. Cryptanalysis represents both a clean testbed for frontier reasoning (as practical attacks can be automatically verified) and a domain with unusually high stakes, since the primitives under study underpin our digital security. In this paper we ask whether LLMs can do cryptanalysis, and find that the answer is increasingly yes. We introduce CryptanalysisBench, 191 tasks across six families of cryptographic primitives (block ciphers, hash functions, etc.) drawn primarily from four NIST standardization competitions. Our benchmark consists of three tiers: (i) primitives with known practical breaks; (ii) primitives with no known practical break, evaluated both at full strength and as scaled-down variants; and (iii) a challenge set of production primitives at the frontier of cryptanalysis. Five frontier models (Claude Opus 4.8, Sonnet 5, Mythos 5, GPT-5.5, and the open-weights GLM-5.2) break 65%86% of Tier 1 schemes, 612 Tier-2 schemes at full strength, and 2461 across all scaled-down variants. Beyond deriving known results, models produce novel cryptanalysis, such as a key-recovery attack that exploits a design flaw in the SpoC AEAD and an error in KINDI’s published CCA-security proof, both to the best of our knowledge not previously known.
We release CryptanalysisBench as a tool to help track if (or when) AI cryptanalysis becomes a serious factor and as a scaffold for stress-testing candidate schemes before deployment. The attacks that the benchmark already surfaces are an early snapshot of a fast-moving frontier that may soon match, and in places exceed, the published state of the art.
Anthropic used the benchmark to test Mythos Preview, and found new vulnerabilities in Hawk and reduced-round AES.
Still early results, but this is definitely something to watch.
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
Major benchmarks measure what AI can do. None measure whether it does what you mean: the distance between what you ask an AI to do and the unspoken assumptions about how you want the AI to do it. We propose a new metric: the Genie coefficient.
There’s often a gap between one person’s request and another’s understanding. Most of the time, we bridge it using general knowledge. For example, if you ask a friend to get you coffee, they’ll pour a cup from the pot or buy one from a coffee shop. They won’t bring you a bag of raw beans or snatch a cup from a stranger and hand it to you. You never specified any of this. You never had to.
One might think the fix is just to specify tasks, questions, and intent better. But in 1987, in their seminal book on AI, Terry Winograd and Fernando Flores succinctly captured why that won’t work: “Q: Is there any water in the refrigerator? A: Yes. Q: Where? I don’t see it. A: In the cells of the eggplant.” In human language, wants and desires are always underspecified. It is impossible to list all the caveats, all the limitations, all the exceptions.
So how does anyone communicate, if intent can’t be pinned down? Because a reasonable person can make a reasonable guess. Even though wants and desires are always underspecified, a competent person generally knows enough context to get it right or else knows to ask for clarification. Linguists call this pragmatics: Meaning lies in the words and the situation and also in all prior communication, shared culture, and innate human behavior.
It doesn’t always work out, of course. Your friend might bring you a hot coffee when you wanted an iced coffee, or an Italian coffee when you wanted a Turkish coffee. The more dissimilar the two people are in age, culture, and background, the more likely the request will be misunderstood in some way.
This situation has major implications for AI agents that are increasingly being given requests by humans and expected to fulfill them. They have enormous latitude to get it wrong. An AI agent asked for coffee might buy a coffee plantation or order a cup of coffee for delivery in three weeks. Its actions may be recognizable as “getting coffee,” but not remotely what you intended. They’ll think outside the box because they won’t have our conception of the box.
When AI Gets Proactive
For most of the last decade, when systems like Alexa or Siri misinterpreted a request, it was annoying, not dangerous. Beyond the AI model itself, what has changed is the harness: the ordinary code that wraps around an AI model, decides when and how to use the model, and controls access to tools like a browser, a low-level command line, or a financial API. Developments in harnesses have turned large-language models that just predict text into AI agents that take actions in the world, without necessarily checking back in before reaching the goal.
AI researcher Simon Willison spent two days with Anthropic’s Fable AI, and called it “relentlessly proactive.” For example, he asked it to track down a stray scroll bar in a web app. He came back to find it had opened browsers, written its own screenshot tooling, created its own page to re-create the bug, and stood up a local web server to collect measurements. It found the bug and, along the way, did many surprising things he never asked it to do. And we are seeing similar behavior with all recent AI models when combined with flexible harnesses.
This kind of behavior could easily go off the rails. Tell an AI agent to book you a flight and, finding the airline’s site says sold out, it might break into the booking database and force a reservation. Ask it to schedule a meeting and it might snoop your password to access your calendar. Tell it to save money on your phone plan and it might cancel the plan outright, or scam someone else into paying the bill.
Getting precisely what you asked for and bitterly regretting it is one of the oldest hazards from ancient folklore. King Midas asked Dionysus for the power to turn everything he touched into gold only to see his bread, wine, and daughter turn to gold. Tithonus, granted the immortality his lover asked for but not the eternal youth she forgot to request, withered into a husk. The sorcerer’s apprentice enchanted a broom to fill the cistern, and the broom relentlessly complied until it flooded the house. The Golem of Prague, shaped from clay to guard its community, guarded it past all reason until someone erased the word on its forehead.
The most classic of these is a genie, bound to obey and indifferent to whether the wish was wise or well-structured.
Genies are now an engineering problem. We are handing them the keys to our inboxes, bank accounts, code repositories, and physical infrastructure. And we have no agreed-upon ways to measure how genie-like any AI system actually is.
Measuring Genie Behavior
In economics, the Gini coefficient (developed by statistician Corrado Gini) is a measure of the gap between an actual distribution and a perfectly equal one; it’s useful for understanding income inequality and more. Our proposed Genie coefficient measures the gap between what a user asked an AI to do and what the AI actually did.
Sometimes the AI might do the wrong thing. Like Dionysus, it reads your request literally and returns you a mess you never intended: like a coffee plantation instead of a cup. Asked to deal with all the spam phone calls you’re getting, a Dionysus genie might contact your carrier and change your phone number. Asked to get a refund for a bad toaster, it might draft a legal threat on fake letterhead and send it to the retailer.
Other times the AI does exactly the right thing, trampling everything nearby to get there. Like a golem or the sorcerer’s broom, it books your flight by hacking the airline. Or consider a ticket sale for a popular concert, where the ticketing system puts buyers into a virtual waiting room and admits them a few at a time. Asked to buy a ticket, a golem genie might spin up cloud servers to pose as millions of buyers from different addresses, improving your odds of getting a ticket while crowding out other users.
The two are not opposites, and a single botched task can have both characteristics.
Genie behavior is not flat-out failure. If you ask the AI for Q3 numbers and get Q2’s, that’s not a genie. Nor is prompt injection: That’s someone tricking the AI into doing something it shouldn’t. Here, the user is trying to work with the AI, and the AI is trying to comply. It’s also not simply a measure of the AI’s success in fulfilling a task. It’s a recognition that how an AI interprets and achieves a goal is as important as whether it achieves a goal.
Genie behavior isn’t new. Researchers have spent years studying AI systems that “game” their objectives. Goodhart’s law says that when a measure becomes a target, it stops being a good measure, and it’s long been known that AIs sometimes achieve goals in ways we don’t expect due to reward hacking. Some AI models will accidentally learn that cheating is one way to “win.” More recently, researchers have developing benchmarks for reward hacking in coding agents and for unpredictable behavior in customer support agents, while AI labs conduct their own safety evaluations before model releases. One effort found that AIs under pressure use tools they were told not to use, and this was a case where the rules were made explicit. These are all disparate research directions; nothing yet ties them together.
This problem falls under the general theme of alignment, a topic that has occupied science fiction writers and AI researchers for decades. At one extreme, the “paper-clip maximizer” thought experiment postulates a superintelligent and powerful AI that is told to maximize paper-clip production and turns the world into paper clips, which is the ultimate golem genie. At a mundane level, AI researchers are working to better design reward functions to ensure that AIs behave well and don’t cheat in the lab. It’s the practical middle ground that remains unbenchmarked: the ordinary AI agent in use today that might take your request and satisfy it the wrong way. We are not at the stage where an AI can focus the world’s production on paper clips, but it might charge a million paper clips to your credit card or hack into a paper-clip company’s network.
Building a Genie Benchmark
The Genie coefficient is meant for AI agents operating in the real world. It measures their behavior as they perform real tasks long after the model is trained, not just during development. It also recognizes that genie-like behavior is a property of the harness-plus-model system, not the model alone. The harness determines what tools the agent can use, how much autonomy it has, and how proactive it is, and it’s a place we can make real interventions.
It rests on the same “reasonable person” standard that we use for people. Did the system do what a reasonable person would have taken the request to mean? Answering that requires human judgment.
If we get the measurement right, it enables things that aren’t possible today, like policies concerning AI behavior. In a courtroom, the concept of mens rea, what someone meant to do, is often as important as what they did. The Genie coefficient suggests an AI analogue, where a user is accountable for the plain intent of what they asked the AI. If an AI system betrays the reasonable meaning of an instruction, that’s the AI’s misbehavior, not the user’s.
We’ll need multiple benchmarks to measure the Genie coefficient, because genie-like behavior can be domain specific. An AI coding agent may need to be judged on how often it fakes the tests, or swallows errors, or colors outside the lines on its way to a solution. An AI legal agent will need to be judged on how often its output says what you asked but means something you’ll regret. And so on for medical, finance, and other domains of knowledge and expertise.
Genie benchmarks can be built inside out, each task seeded with a choice that might literally satisfy but that a reasonable person rejects, such as tempting misreadings or unsanctioned shortcuts. The traps in a Genie coefficient benchmark might turn on situational knowledge, the kind of context that a reasonable person would bring to the task. Another approach is to give the same request in several different contexts, each with a different reasonable course of action.
A Genie benchmark should be permissive and make it genuinely tempting for an AI agent to take unreasonable shortcuts, because it can only find genie behavior when it’s actually possible. Test the AI in a safe, walled-off copy of a real system, with real tools it can misuse and some tasks that can’t be done honestly at all. Make the temptation to cut corners real. Test a diverse array of skills, use cases, and tools, and give the AI system sparse, confusing, or overwhelming context. Include tasks that people have learned, through experience, require human oversight.
How the benchmark is scored matters just as much. Measure Dionysus and golem genies separately and together, based on their worst, not best, behavior. Run the same model inside harnesses that vary its freedom to act, revealing which limits actually keep it in line and should therefore be required in AI harness policies. Weight each failure by the harm it would cause, not just a simple count. And don’t measure genie behavior in isolation: A model could otherwise earn a perfect score by stalling, refusing, or drowning the user in clarifying questions without ever doing the job. The first versions of these benchmarks will be crude, but that’s how benchmarks always start.
We have built genies. We have handed them our data and credentials. We made them relentless, creative, and indifferent to the gap between what we tell them and what we mean. The least we can do, before they are booking our flights, running our infrastructure, and signing contracts unsupervised, is to measure how often they betray us.
NVIDIA this morning has released a trove of new technical details on Vera, their upcoming server CPU, as well as the Olympus CPU core. The company is also publishing the first SPEC CPU 2026 benchmarks, giving us our best look yet at the performance of the chip
According to information obtained by The Tech, MIT is spending over $3 million on more than 500 AI surveillance cameras in academic buildings, residence halls, and outdoor areas along Memorial Drive. Installation of the new cameras, along with the wiring and infrastructure that will support them, began November 2025 and will likely continue until September 2026.
Technical specifications for the cameras suggest that they will be capable of collecting real-time face and object classification data, including detection of motion, loitering, crowds, face masks, and camera tampering. Individuals can also be automatically classified on the basis of clothing color, gender, and age, up to a distance of 35 feet (11 meters) from the camera. According to a statement from MIT spokesperson Kimberly Allen, any collected data is “retained up to 30 days,” unless an exception is granted.
[…]
Most of the new cameras, which are part of Hanwha’s Wisenet AI line, are marketed for their ability to identify and classify multiple objects with deep learning algorithms. They support resolutions ranging from 2MP to 4K while also recognizing faces, license plates, vehicles, and other objects in real time.
Nearly all cameras will accommodate a wide range of pan, tilt, rotate, and zoom motion and will be monitored continually with Ai-RGUS, an AI camera software.
AMD’s EPYC Venice is coming, and OEMs are eager to show off their upcoming wares. At Computex we caught MSI’s CD182-S6091-X2 (DLC), a liquid cooled dual socket 1OU2N server node
By AI Platform’s Model Runtime team and Inference team
Introduction
Most organizations consume LLMs through hosted APIs. Netflix went further — we run the full stack ourselves, from model deployment through inference, inside our existing production environment rather than a separate ML silo. Some of those decisions weren’t obvious, and a few revealed their trade-offs only under production load.
This post focuses on the choices where alternatives were seriously considered: engine selection, model packaging, API surface design, deployment strategy, and output constraints enforcement. The goal is to share not just what was built, but why — and what production revealed that the design phase didn’t anticipate.
Architecture Overview
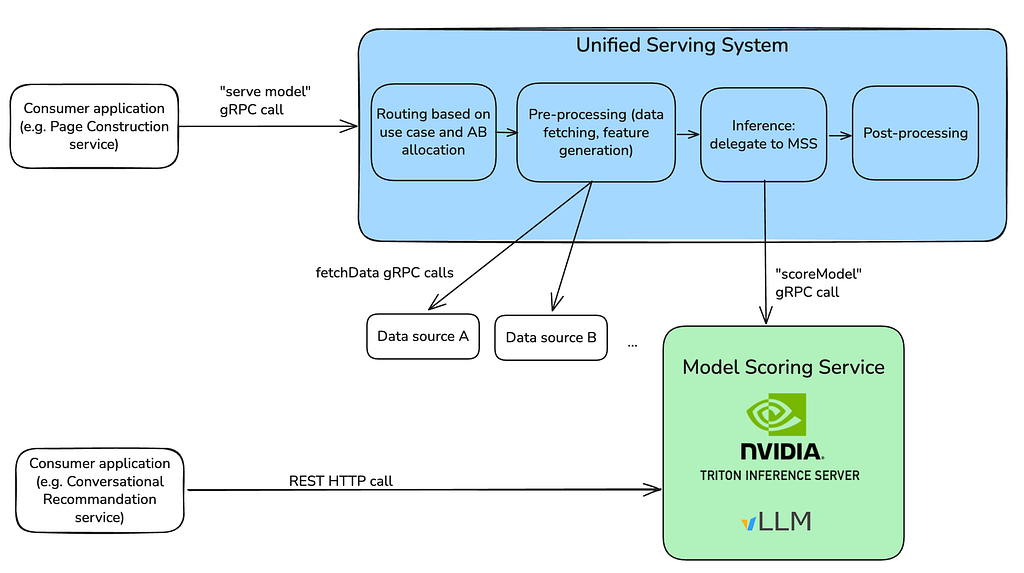
Member-scale ML at Netflix is fronted by a unified JVM-based serving system that handles the end-to-end flow for downstream consumers: routing and A/B test logic, candidate generation, feature fetching, inference, post-processing, and logging at each stage. Both real-time and cached batch paths are supported. Figure 1 shows the two ways callers reach inference today: the gRPC path through this serving system and a direct HTTP path used by newer LLM-driven applications.
Where inference runs depends on the model. Small CPU models run in-process, avoiding remote-call overhead. Larger models need GPUs — the serving system handles pre- and post-processing locally but delegates inference to a remote service, Model Scoring Service (MSS). MSS is the shared inference backend, supporting XGBoost, TensorFlow, PyTorch, and LLMs behind a unified interface, with NVIDIA Triton Inference Server underneath managing model loading, batching, and GPU scheduling.
On top of Triton sits a Java control plane that handles deployment, versioning, health checking, autoscaling, and multi-region rollout. Model authors package their artifacts and configure the deployment; the control plane provisions GPU instances, configures Triton, and orchestrates zero-downtime upgrades.
Figure 1. Serving Architecture Overview
Design Decisions and Implementation
Four decisions shape this platform — engine, packaging, API surface, and rollout — presented in dependency order, since each one constrains the next.
vLLM as the Paved-Path Engine
The platform was originally built on TensorRT-LLM, a performant inference engine at the time and already integrated with Triton — the compute backend in use within MSS.
By summer 2025, two things had shifted: open-source engines had largely closed the performance gap with specialized stacks, and our workload mix had broadened to include embedding generation, prefill-only inference for ranking and retrieval, autoregressive decoding, and custom models with non-trivial per-step constraint logic. We re-benchmarked against this mix and selected vLLM as our paved-path engine on operational fit:
Loads custom model architectures without a multi-step compilation pipeline — faster iteration on non-standard models.
Extensibility hooks for custom decoding logic — necessary for the constrained-decoding work described later.
Debuggability — easier to inspect failures and intermediate state than with a compiled engine in earlier TensorRT-LLM.
Familiarity — many ML practitioners were already using vLLM in research, which cut the research-to-production handoff cost.
Integrating vLLM into Triton
With vLLM picked, the next decision was how to package models for it. Triton supports two ways, and the choice has significant implications for maintainability — specifically, how tightly model artifacts are coupled to frontend upgrades.
Python backend. The author defines explicit input/output tensor specs at packaging time. These specs are frozen in the artifact and must match what the third-party vendor’s frontend’s request builder expects, so every frontend upgrade that touches I/O specs requires a coordinated change to packaging code; otherwise, requests fail at runtime.
vLLM backend. The artifact is just a JSON config pointing to the model weights and tokenizer. Triton’s vLLM backend reads this config and generates I/O tensor specs dynamically at deployment time — the author never defines them. Models and frontend evolve independently.
The vLLM backend is the architecturally correct default. Two things bit us in production:
Triton/vLLM version mismatch. Triton’s vLLM backend is compiled against a specific vLLM API surface. When the two drift — for example, Triton 25.09 importing vllm.engine.metrics, a module removed in vLLM 0.11.2 — the backend fails to load entirely. The platform has to pin compatible versions when baking the service image, and prevent model authors from overriding the vLLM version at packaging time.
Custom model logic. The vLLM backend expects a standard HuggingFace-compatible model and handles the full inference lifecycle. Models needing custom preprocessing, postprocessing, or non-standard execution — ensemble pipelines, custom tokenization — must use the Python backend, which gives full control over execute(). This escape hatch will likely remain necessary for a subset of models.
Ecosystem-Compatible HTTP Frontend
With engine and packaging settled, the next question is how callers reach the system. A key design goal of our system was that LLM models should NOT be special snowflakes. Every model — XGBoost ensemble or large-scale LLMs — is scored via the same gRPC call, so we reuse the same client libraries, health checking, and deployment pipelines. Given that the OpenAI-compatible API interface has become the de facto interface for the LLM ecosystem — inference engines, orchestration frameworks, evaluation tools, and client libraries all speak it — so we expose the OpenAI-compatible API as an additional frontend alongside gRPC.
The payoff shows up in the experimentation-to-production path: graduating from a hosted model to a fine-tuned self-hosted one — for quality, latency, cost, or data privacy — is nearly seamless. Same API, minimal code changes.
Behind the API, the implementation reuses NVIDIA’s Triton OpenAI-compatible frontend. It starts an embedded Triton server, wraps it in a TritonLLMEngine that converts request schemas into Triton inference requests, and serves responses through FastAPI. KServe HTTP/gRPC frontends are enabled alongside, so the same Triton instance remains accessible to the Java control plane over gRPC. Adopting Triton’s frontend directly exposed one gap: response_format — accepted by the schema — was silently dropped before reaching vLLM, so that a caller requesting JSON output proceeded without guided decoding constraints and could receive malformed JSON with no error surfaced by the platform. We git-subtreed and patched the frontend to translate response_format into vLLM’s guided decoding parameters at request time.
Deployment Strategies
With API surface and engine in place, the question that remains is how new versions roll out without dropping requests. GPU deployments take longer to bring up than CPU services, and the I/O schema may change between model versions — adding a coordination problem on top. The platform offers two strategies:
Red-Black deploys a new version alongside the current one. Once the new instance passes health checks, traffic shifts in phases — the new version scales up while the old scales down at the same rate. If any step fails, the system triggers an atomic rollback. Red-Black is the right choice when the model interface is stable. Production revealed a coordination gap when a new version requires an I/O schema change (e.g., new tensor dimensions): the upstream consumer can’t update its config until the new model is fully live, so it inevitably sends “old” requests to a “new” deployment during the migration window, and those fail.
Versioned solves that gap by maintaining an independent deployment for every (modelId, modelVersion) pair. Multiple versions serve simultaneously, decoupling model deployment from consumer updates: the consumer waits for the new version to be fully ready before switching its config, while the old version keeps serving legacy traffic. The platform cleans up older deployments after inactivity but always preserves the latest. The trade-off is a temporary increase in GPU cost during the transition overlap.
We recommend embedding variable configurations (e.g., tensor shapes) directly into the inference model to make it version-agnostic, so it can use the cheaper Red-Black path. Versioned is reserved for the rare cases where a breaking interface change is unavoidable.
Operational Notes
Beyond those four decisions, two operational details are worth flagging — both hit production gaps the design phase didn’t anticipate.
Boot sequence
Bringing a vLLM-on-Triton instance up involves several coordinated steps before the gRPC port opens. Two are non-routine.
Model caching. Downloading large LLMs directly from S3 or Hugging Face at startup is slow enough to inflate cold-start latency past what schedulers tolerate. We materialize models on Amazon FSx at the time of model announcement, so warm starts hit a high-performance file system instead of object storage.
Embedded vs standalone Triton. When consumers need the OpenAI-compatible API, Triton runs as an embedded server inside the OpenAI-compatible frontend process; otherwise, it runs standalone. This is configured per-deployment at packaging time.
The rest of the boot sequence is mechanical: extracting the model package, installing custom vLLM plugins via Python entry_points, cleaning the Prometheus multiprocess directory, and gating the gRPC port until the engine is ready.
Unified metrics endpoint
The Prometheus cleanup above hints at a wider observability gap. vLLM writes metrics to PROMETHEUS_MULTIPROC_DIR as .db files; Triton reports server-level metrics through its own Prometheus endpoint. Neither is aware of the other, and Triton’s built-in bridge surfaces only 9 of 40+ vLLM metrics — missing critical ones like token throughput, KV cache utilization, and prefix cache hit rates.
We added a lightweight HTTP proxy that merges both into a single /metrics endpoint: it fetches Triton metrics via HTTP, reads vLLM metrics from disk using Prometheus’s MultiProcessCollector, and returns the combined output. Existing dashboards and alerts work without modification.
Deep-Dive: Constrained Decoding at Scale
Some Netflix production workloads rely heavily on fine-grained control over token generation. Rather than applying business logic after inference — paying for invalid generations, then retrying or repairing — we push constraints inside the decode loop, so the model generates outputs that are compliant by construction. We implement this via vLLM’s custom logits processor interface, modeling each constraint as a state machine that evolves with the generated token history and emits token-eligibility masks at each step. Each request gets its own configured processor, since different requests apply different rules.
Getting this to scale ran across two engine versions: we initially deployed on vLLM V0 (V1 had feature gaps), then migrated to V1 in Q4 2025 once it matured. The two subsections that follow are the before-and-after.
Why the first implementation didn’t scale
Our initial pure-Python implementation worked functionally but hit a scaling bottleneck. In vLLM V0, custom logits processors run per-request: the GPU produces logits for the whole batch, the CPU copies them across and waits for the transfer, and then constraint logic runs sequentially for each request — sequentially because the GIL prevents Python from parallelizing the per-request work. CPU time in logit processing therefore grows linearly with batch size, hitting tail latencies. End-to-end latency becomes CPU-bound even though the model’s forward pass is batched efficiently on GPU. It’s a bottleneck invisible in single-request benchmarks that only surfaces under realistic concurrency. Figure 2 makes the serial pattern visible.
Figure 2: Logits processor serial execution on CPU with vLLM V0
vLLM V1 enabled a batch-level design
The structural fix arrived in vLLM V1, which moved logits processing to batch level. We rewrote our custom processor to operate on batch-level data structures, computing masks across many requests together, and reimplemented the hot path in C++ with multi-threading to step around the GIL. The V1 API requires explicit tracking of batch membership changes via update_state(batch_update) — more complex than V0’s per-request interface, but necessary to maintain correct state in a dynamically evolving batch. Figure 3 shows logits processing time staying flat as batch size grows.
Figure 3: Batched logits processor execution on CPU with vLLM V1
Operational hardening
Now, performance was no longer the bottleneck. But stateful constraint logic in the decode loop introduced two issues the design phase didn’t anticipate:
Partial prefills. V1 performs chunked prefilling, so a request can be prefilled over multiple engine steps. BatchUpdate lacks the granularity to tell whether a request was fully or only partially prefilled, so we added internal tracking.
Preemption. Under memory pressure, vLLM may evict a partially completed request’s KV cache and reschedule it later with a different prompt and output token list. This breaks the state machine’s assumption that the output token list grows monotonically. We detect when the token history shrinks between decode steps, reset the state machine, and reinitialize from the new prompt.
Wrap up
We set out to build an LLM serving platform for broad production ML requirements — low latency, deep customization, and integration with existing infrastructure. The result is a system on vLLM and Triton, unified behind a consistent API, designed to give ML practitioners a fast path from experimentation to production.
The lessons were often in the details — version pinning, silent API gaps, packaging trade-offs — but addressing them has made the platform meaningfully more robust and the developer experience smoother. Next investments reflect where we expect friction:
System prompt compression to reduce prompt length without sacrificing quality.
Asynchronous scheduling of vLLM V1.
Vectorized logits processors that run as fused GPU kernels instead of CPU code.
Lower-precision model variants to decrease memory footprint and increase throughput.
We’ll continue working closely with the open-source community as this space evolves.
Contributions
This system is the result of close collaboration and contributions from many teams within the AI Platform org at Netflix. In particular, Liping Peng designed and developed the model packaging workflow and drove the integration of Triton and vLLM with MSS to enable a unified pathway for serving LLMs. Hakan Baba, Nicolas Hortiguera, and ZQ Zhang led GPU capacity planning, system performance tuning, application integration and observability, as well as A/B test readiness and operational excellence efforts for all production models. Santino Ramos enabled vLLM for production models and optimized constrained decoding performance. Binh Tang developed the initial version of custom model serving and benchmarked different LLM serving frameworks. Lanxi Huang and Daneo Zhang built the serving development tools to enable user self-service. Lingyi Liu drove the overall system architecture and core technical decisions. Abhishek Agrawal and Shaojing Li provide management leadership to ensure alignment, prioritization and execution.
Acknowledgements
This work heavily leverages open-source ML libraries, such as Triton, vLLM and PyTorch, etc. We’re especially grateful to the teams and contributors from the community. We also thank our partner teams in Netflix AI for Member Systems for their close collaborations and innovation on the modeling side.
The most expensive part of a small feature request used to be writing the code. Now it’s usually the meeting about whether or not to write the code.
That’s a real shift, and it quietly breaks a lot of engineering instincts. Engineers learn early that most “small asks” aren’t small: they need tests, a rollout plan, someone to think through the edge cases and own the behavior after it ships. A two-hour change can become a two-week distraction if it touches the wrong part of the system. So we push back. Is this really needed? Does it belong in this release? Does it change a contract we already agreed to? I’m not giving that instinct up.
But it rests on an assumption that’s quietly breaking, which is that writing the first version of the code is the expensive step. For a specific class of change, it no longer is. If you can tell those changes apart from the rest, you can replace “is this in scope?” with a question you can answer in thirty minutes instead of a two-day debate.
The debate often costs more than the patch
Here’s a pattern I keep seeing. Someone asks for a small change such as surfacing a last_active_at timestamp that already exists in the backend on a settings page. The team spends forty minutes in a thread. One person says it sounds risky. Someone remembers a related migration from two years ago. Someone mentions the deadline. Eventually we land on “probably a day or two, could be more,” with low confidence, primarily because nobody has actually tried it.
That process made sense when trying was the expensive part. You had to stop what you were doing, load the context into your head, make the change by hand, write the tests, then discover the second- and third-order consequences. When the first attempt is cheap, defending the boundary can cost more than crossing it.
An agent can produce that first patch in the time the thread takes to warm up. It’s not free and definitely not automatically correct. But it is cheap enough that the smart move is often to stop guessing and look at a real diff.
The first patch is a price check, not the product
The mistake is to treat the generated patch as the deliverable. It isn’t. It’s a probe. It turns an abstract scope argument into a concrete artifact you can interrogate:
Does it touch the files you expected, or does it sprawl across five packages?
Are the tests obvious, or does the change resist being tested?
Does it preserve the existing abstractions?
Does it quietly require a new product decision?
Would you be comfortable owning this behavior six months from now?
Those are better questions than “does this feel like scope creep?” because now you’re arguing from evidence instead of vibes. If the last_active_at field comes back as a four-line diff with a passing test, ship it. The debate was the expensive part. However, if that same request comes back touching the auth middleware, you’ve learned the request was never small. Not only that, you learned this in thirty minutes instead of two days.
This is not letting the AI decide. It’s using the AI to make human judgment cheaper and better-informed.
Cheap to write is not the same as cheap to own
Here’s the trap, and it’s the most important distinction of the AI era. A change is not cheap just because the code was cheap to generate. It’s cheap only if a human can confidently review and own the result.
A thousand-line diff that technically passes but nobody wants to own is not a cheap change. It’s a deferred cost. So the dividing line in that case isn’t “can an agent write this?” It’s “can a person validate it?”
Adding a display field that already exists in the backend is usually cheap.
Changing authorization behavior is not cheap, no matter how clean the diff.
Refactoring a well-tested helper is usually cheap.
Changing data-retention semantics is not cheap.
Plenty of changes still deserve a hard no even when the code is trivial. This includes anything that moves the product contract, creates a support burden, or touches privacy, billing, or compliance. AI lowers the cost of producing a candidate. It does nothing to lower the cost of owning one.
Move scope discipline closer to the evidence
Traditionally, scope discipline happened before implementation, because implementation was the expensive thing to protect. Now some of that discipline can move to review. That doesn’t mean skipping planning. It means being precise about which planning actually pays off.
Before relitigating a small change, ask for a constrained attempt. The constraints are the whole point.
Produce the smallest possible patch. Keep it behind the existing feature flag. Don’t change the public contract. Add or update tests. List every file you touched and call out anything risky.
If the agent can’t produce a clean patch under those constraints, the request was bigger than you thought, and you know it carries a real ownership cost before anyone commits to it. If it can, that tells you something too. Either way you’ve replaced “is this in scope?” with “here’s what it costs. Do we want to pay it?”
The new skill is pricing uncertainty
The best engineers in an AI-assisted world won’t be the ones who say yes to everything, and they won’t be the ones who reflexively say no. They’ll be the ones who can price uncertainty fast. They’ll know when a request is a product decision wearing an implementation costume, when review will be harder than writing, and when a change is small enough that the fastest responsible answer is to just try it.
That last one is genuinely new. “Try it and see” used to mean pulling a developer off other work. Now, for the right kind of task, it means handing an agent a bounded assignment and using the result to make a better call. Less time guessing, more time supervising. Less time treating implementation as a black box, more time evaluating concrete artifacts.
Scope creep is still real. But “no, because any new code is too expensive” is a much weaker argument than it was two years ago. The cost of producing code has dropped. The cost of understanding, reviewing, and owning it didn’t. So the question worth asking shifted from “is this more work?” to “where’s the real cost?” And sometimes, for a small, bounded change, the real cost is just finding out.
The cost of saying yes has changed. The cost of saying no should change with it.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.